diff --git a/lm-evaluation-harness/tests/testdata/pile_pile-cc-v0-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_pile-cc-v0-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..d5369ed3c97838d67c2900cfac4aaeb5881ec884
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_pile-cc-v0-loglikelihood_rolling
@@ -0,0 +1 @@
+731fdef4a43949b179ba0c540148ebc2fa41583dd583ef580dd812076c66a451
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_pile-cc-v1-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_pile-cc-v1-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..d5369ed3c97838d67c2900cfac4aaeb5881ec884
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_pile-cc-v1-loglikelihood_rolling
@@ -0,0 +1 @@
+731fdef4a43949b179ba0c540148ebc2fa41583dd583ef580dd812076c66a451
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_pile-cc-v1-res.json b/lm-evaluation-harness/tests/testdata/pile_pile-cc-v1-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..bd2772e32a91a6518ed2eb48ef880827f5246adf
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_pile-cc-v1-res.json
@@ -0,0 +1 @@
+{"results": {"pile_pile-cc": {"bits_per_byte": 0.0001620742639125056, "byte_perplexity": 1.0001123476295946, "word_perplexity": 1.0006738958554477}}, "versions": {"pile_pile-cc": 1}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_pubmed-abstracts-v0-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_pubmed-abstracts-v0-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..de5660d60a8d4f0d5e35d47008992befed318d28
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_pubmed-abstracts-v0-loglikelihood_rolling
@@ -0,0 +1 @@
+66436569a43163afb2caf422d32c5f329899e74c49865d4d13881fd465fd9976
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_pubmed-abstracts-v0-res.json b/lm-evaluation-harness/tests/testdata/pile_pubmed-abstracts-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..333c2970fa21b0bd53b77bdc3880acad0c8d6459
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_pubmed-abstracts-v0-res.json
@@ -0,0 +1 @@
+{"results": {"pile_pubmed-abstracts": {"bits_per_byte": 0.00037553733051528816, "byte_perplexity": 1.0003756078534862, "word_perplexity": 1.0025884332779}}, "versions": {"pile_pubmed-abstracts": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_pubmed-abstracts-v1-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_pubmed-abstracts-v1-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..de5660d60a8d4f0d5e35d47008992befed318d28
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_pubmed-abstracts-v1-loglikelihood_rolling
@@ -0,0 +1 @@
+66436569a43163afb2caf422d32c5f329899e74c49865d4d13881fd465fd9976
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_pubmed-abstracts-v1-res.json b/lm-evaluation-harness/tests/testdata/pile_pubmed-abstracts-v1-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..21b6bb451fe376e62899f22ea422b3ce9cada469
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_pubmed-abstracts-v1-res.json
@@ -0,0 +1 @@
+{"results": {"pile_pubmed-abstracts": {"bits_per_byte": 0.0005417858444030858, "byte_perplexity": 1.0003756078534862, "word_perplexity": 1.0025884332779}}, "versions": {"pile_pubmed-abstracts": 1}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_pubmed-central-v0-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_pubmed-central-v0-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..283109f32e0aac45adcbc90c7c8fb41114e7771f
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_pubmed-central-v0-loglikelihood_rolling
@@ -0,0 +1 @@
+40b39d120d99a145690444e86acc3e3e24d41e6e0538a75e26929ad84926e5e0
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_pubmed-central-v0-res.json b/lm-evaluation-harness/tests/testdata/pile_pubmed-central-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..6e5f1efe495f7030764f96e45460a4d47315b1e3
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_pubmed-central-v0-res.json
@@ -0,0 +1 @@
+{"results": {"pile_pubmed-central": {"bits_per_byte": 1.5812411832795375e-05, "byte_perplexity": 1.0000158125368497, "word_perplexity": 1.000123107107861}}, "versions": {"pile_pubmed-central": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_pubmed-central-v1-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_pubmed-central-v1-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..283109f32e0aac45adcbc90c7c8fb41114e7771f
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_pubmed-central-v1-loglikelihood_rolling
@@ -0,0 +1 @@
+40b39d120d99a145690444e86acc3e3e24d41e6e0538a75e26929ad84926e5e0
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_pubmed-central-v1-res.json b/lm-evaluation-harness/tests/testdata/pile_pubmed-central-v1-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..4d4a241ace01e28f15cd7bd88d3f855b1bf5372d
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_pubmed-central-v1-res.json
@@ -0,0 +1 @@
+{"results": {"pile_pubmed-central": {"bits_per_byte": 2.2812488135667854e-05, "byte_perplexity": 1.0000158125368497, "word_perplexity": 1.000123107107861}}, "versions": {"pile_pubmed-central": 1}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_stackexchange-v0-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_stackexchange-v0-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..dcf0e64cf0d4bf4fe719b8d349c1d36484d2047f
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_stackexchange-v0-loglikelihood_rolling
@@ -0,0 +1 @@
+e524bfb3e21cbdaddc117403a50df598520c7bf5b2c60ad8f2372cfa564e79be
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_stackexchange-v0-res.json b/lm-evaluation-harness/tests/testdata/pile_stackexchange-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..76fdd0a6dd2f8ca39611601c5cb514664d5dccbc
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_stackexchange-v0-res.json
@@ -0,0 +1 @@
+{"results": {"pile_stackexchange": {"bits_per_byte": 0.0002288815898835956, "byte_perplexity": 1.0002289077852733, "word_perplexity": 1.0016993562258851}}, "versions": {"pile_stackexchange": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_stackexchange-v1-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_stackexchange-v1-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..dcf0e64cf0d4bf4fe719b8d349c1d36484d2047f
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_stackexchange-v1-loglikelihood_rolling
@@ -0,0 +1 @@
+e524bfb3e21cbdaddc117403a50df598520c7bf5b2c60ad8f2372cfa564e79be
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_stackexchange-v1-res.json b/lm-evaluation-harness/tests/testdata/pile_stackexchange-v1-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..2773302990f71e46f7f44f5d2e2b624a52ddb54d
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_stackexchange-v1-res.json
@@ -0,0 +1 @@
+{"results": {"pile_stackexchange": {"bits_per_byte": 0.0003302063346758449, "byte_perplexity": 1.0002289077852733, "word_perplexity": 1.0016993562258851}}, "versions": {"pile_stackexchange": 1}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_ubuntu-irc-v0-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_ubuntu-irc-v0-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..ce041998635643ee17aace3105b227ef0746917e
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_ubuntu-irc-v0-loglikelihood_rolling
@@ -0,0 +1 @@
+4eb69e314f0864ec8890e2323d7e76f8a8309692c4f090e2b41bf4be681a811d
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_ubuntu-irc-v0-res.json b/lm-evaluation-harness/tests/testdata/pile_ubuntu-irc-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..dff51cba766a795077324ffe9bf71d786dbb695a
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_ubuntu-irc-v0-res.json
@@ -0,0 +1 @@
+{"results": {"pile_ubuntu-irc": {"bits_per_byte": 1.6298315496830533e-06, "byte_perplexity": 1.0000016298328778, "word_perplexity": 1.0000108866656874}}, "versions": {"pile_ubuntu-irc": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_ubuntu-irc-v1-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_ubuntu-irc-v1-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..ce041998635643ee17aace3105b227ef0746917e
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_ubuntu-irc-v1-loglikelihood_rolling
@@ -0,0 +1 @@
+4eb69e314f0864ec8890e2323d7e76f8a8309692c4f090e2b41bf4be681a811d
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_ubuntu-irc-v1-res.json b/lm-evaluation-harness/tests/testdata/pile_ubuntu-irc-v1-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..0e3b1b25977cc5c7eba81358df76e7ed45d1b04a
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_ubuntu-irc-v1-res.json
@@ -0,0 +1 @@
+{"results": {"pile_ubuntu-irc": {"bits_per_byte": 2.3513498942121155e-06, "byte_perplexity": 1.0000016298328778, "word_perplexity": 1.0000108866656874}}, "versions": {"pile_ubuntu-irc": 1}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_uspto-v0-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_uspto-v0-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..4649d3b9b7f1f17e4731644d470fc0a2651a980d
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_uspto-v0-loglikelihood_rolling
@@ -0,0 +1 @@
+789b2bdb31564d512b70f801316f49320a26c83ba361226bac0afb255341d477
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_uspto-v0-res.json b/lm-evaluation-harness/tests/testdata/pile_uspto-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..c13dfc73f5927415055cf393fb16bd13ba6b1b56
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_uspto-v0-res.json
@@ -0,0 +1 @@
+{"results": {"pile_uspto": {"bits_per_byte": 0.00012062434384130924, "byte_perplexity": 1.00012063161925, "word_perplexity": 1.0007716198916954}}, "versions": {"pile_uspto": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_uspto-v1-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_uspto-v1-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..4649d3b9b7f1f17e4731644d470fc0a2651a980d
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_uspto-v1-loglikelihood_rolling
@@ -0,0 +1 @@
+789b2bdb31564d512b70f801316f49320a26c83ba361226bac0afb255341d477
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_uspto-v1-res.json b/lm-evaluation-harness/tests/testdata/pile_uspto-v1-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..599ae44ef430af958ab53c57d0b7900928ad243a
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_uspto-v1-res.json
@@ -0,0 +1 @@
+{"results": {"pile_uspto": {"bits_per_byte": 0.000174024142670342, "byte_perplexity": 1.00012063161925, "word_perplexity": 1.0007716198916954}}, "versions": {"pile_uspto": 1}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_wikipedia-v0-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_wikipedia-v0-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..e44bd2762803a9b922febf4fe8bfd459e95174b9
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_wikipedia-v0-loglikelihood_rolling
@@ -0,0 +1 @@
+ef9ec0dd408316ca6537228a6812e839f14b30608973081d41efc47c138338da
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_wikipedia-v0-res.json b/lm-evaluation-harness/tests/testdata/pile_wikipedia-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..bfffde9938833ae29f5665130d844630c7fb9735
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_wikipedia-v0-res.json
@@ -0,0 +1 @@
+{"results": {"pile_wikipedia": {"bits_per_byte": 0.00016834722287561703, "byte_perplexity": 1.0001683613940646, "word_perplexity": 1.001084677949439}}, "versions": {"pile_wikipedia": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_wikipedia-v1-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_wikipedia-v1-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..e44bd2762803a9b922febf4fe8bfd459e95174b9
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_wikipedia-v1-loglikelihood_rolling
@@ -0,0 +1 @@
+ef9ec0dd408316ca6537228a6812e839f14b30608973081d41efc47c138338da
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_wikipedia-v1-res.json b/lm-evaluation-harness/tests/testdata/pile_wikipedia-v1-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..4f2314e66b3a5dbd9ed3c25d9e9a97c7d1fbff3d
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_wikipedia-v1-res.json
@@ -0,0 +1 @@
+{"results": {"pile_wikipedia": {"bits_per_byte": 0.00024287370359008176, "byte_perplexity": 1.0001683613940646, "word_perplexity": 1.001084677949439}}, "versions": {"pile_wikipedia": 1}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_youtubesubtitles-v0-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_youtubesubtitles-v0-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..81c2e5ed06321b250a08a4232b3720ea5b650156
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_youtubesubtitles-v0-loglikelihood_rolling
@@ -0,0 +1 @@
+68263c52adc0086011e2220b619983935cabb1cc1f5f9f8ee1a74ab2a7457967
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_youtubesubtitles-v0-res.json b/lm-evaluation-harness/tests/testdata/pile_youtubesubtitles-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..b58ce148f0071707d5da39135aaeb92a2a1457a2
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_youtubesubtitles-v0-res.json
@@ -0,0 +1 @@
+{"results": {"pile_youtubesubtitles": {"bits_per_byte": 2.3447170928931888e-05, "byte_perplexity": 1.000023447445816, "word_perplexity": 1.0001529192262875}}, "versions": {"pile_youtubesubtitles": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_youtubesubtitles-v1-loglikelihood_rolling b/lm-evaluation-harness/tests/testdata/pile_youtubesubtitles-v1-loglikelihood_rolling
new file mode 100644
index 0000000000000000000000000000000000000000..81c2e5ed06321b250a08a4232b3720ea5b650156
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_youtubesubtitles-v1-loglikelihood_rolling
@@ -0,0 +1 @@
+68263c52adc0086011e2220b619983935cabb1cc1f5f9f8ee1a74ab2a7457967
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pile_youtubesubtitles-v1-res.json b/lm-evaluation-harness/tests/testdata/pile_youtubesubtitles-v1-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..fcf2faa8bc7927212fa7c55940849f64d3c48968
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pile_youtubesubtitles-v1-res.json
@@ -0,0 +1 @@
+{"results": {"pile_youtubesubtitles": {"bits_per_byte": 3.3827117222045906e-05, "byte_perplexity": 1.000023447445816, "word_perplexity": 1.0001529192262875}}, "versions": {"pile_youtubesubtitles": 1}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/piqa-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/piqa-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..b01b1fe5d8c699f855bff57061d6d63715c7f058
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/piqa-v0-loglikelihood
@@ -0,0 +1 @@
+6048a3a2bb3ad1e6a3d98139618e06b4d7de766edd685bd38837596199c3f69f
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/piqa-v0-res.json b/lm-evaluation-harness/tests/testdata/piqa-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..bb6ebfb9a268d8fcfd3dd35ecb26fee05a1b8090
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/piqa-v0-res.json
@@ -0,0 +1 @@
+{"results": {"piqa": {"acc": 0.514145810663765, "acc_norm": 0.5114254624591947, "acc_norm_stderr": 0.01166277802645167, "acc_stderr": 0.011661154475524836}}, "versions": {"piqa": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/prost-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/prost-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..a94b8cdec9e45e5b236703414fbcc6a3ed74f7ff
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/prost-v0-loglikelihood
@@ -0,0 +1 @@
+7c475f5b36a8b79f94c2be035441e7fd59dac021b0713b1fc72d256424c70b0b
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/prost-v0-res.json b/lm-evaluation-harness/tests/testdata/prost-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..ff99d83f40a966afe7df30661a3fc4d9dd09c4ca
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/prost-v0-res.json
@@ -0,0 +1 @@
+{"results": {"prost": {"acc": 0.24631725021349274, "acc_norm": 0.2581127241673783, "acc_norm_stderr": 0.00319703079646546, "acc_stderr": 0.003147855968061357}}, "versions": {"prost": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pubmedqa-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/pubmedqa-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..97db87ce2be9b3d2c08479ee73c7ba3923817795
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pubmedqa-v0-loglikelihood
@@ -0,0 +1 @@
+7a04a1fb1d2b19db84fd15c224015d6c0306a41195a4e71fe6abd48fb4d53b9f
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/pubmedqa-v0-res.json b/lm-evaluation-harness/tests/testdata/pubmedqa-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..bb39463a4ab7244109901cbbc06ded3192ee0480
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/pubmedqa-v0-res.json
@@ -0,0 +1 @@
+{"results": {"pubmedqa": {"acc": 0.324, "acc_stderr": 0.01480686473373886}}, "versions": {"pubmedqa": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/qa4mre_2011-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/qa4mre_2011-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..049134c7a1eac7ba79fa86951526a4ca96ddd200
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/qa4mre_2011-v0-loglikelihood
@@ -0,0 +1 @@
+0d09f17c65768e797633494d2d218e4e46a26f718cab8b0bf3d156b073a8c437
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/qa4mre_2011-v0-res.json b/lm-evaluation-harness/tests/testdata/qa4mre_2011-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..601c4eb763d97500cfcd4e24ca6602986c49939c
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/qa4mre_2011-v0-res.json
@@ -0,0 +1 @@
+{"results": {"qa4mre_2011": {"acc": 0.225, "acc_norm": 0.23333333333333334, "acc_norm_stderr": 0.03877199986918664, "acc_stderr": 0.0382797091741014}}, "versions": {"qa4mre_2011": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/qa4mre_2012-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/qa4mre_2012-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..0e67fac5f7d54c19e42cae4cfc850089c7c61187
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/qa4mre_2012-v0-loglikelihood
@@ -0,0 +1 @@
+7e17261820acb365966cb9431d93aec983b14393eaeefbc96e30a11cf58bc6df
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/qa4mre_2012-v0-res.json b/lm-evaluation-harness/tests/testdata/qa4mre_2012-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..91d8f3660413469e7ab00c3af1102392c3e26cc7
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/qa4mre_2012-v0-res.json
@@ -0,0 +1 @@
+{"results": {"qa4mre_2012": {"acc": 0.15625, "acc_norm": 0.16875, "acc_norm_stderr": 0.029702236908328808, "acc_stderr": 0.02879508360159146}}, "versions": {"qa4mre_2012": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/qa4mre_2013-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/qa4mre_2013-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..43243706d9b743cec2965545f3f4436a3e5d7551
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/qa4mre_2013-v0-loglikelihood
@@ -0,0 +1 @@
+52fc431e94c67f983e28ebc70cf45e6c14116b0ae77dc1bf22347c705a65d054
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/qa4mre_2013-v0-res.json b/lm-evaluation-harness/tests/testdata/qa4mre_2013-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..c87e487e9ac147c5a9ba8cb3a4b2a39048d1dcaa
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/qa4mre_2013-v0-res.json
@@ -0,0 +1 @@
+{"results": {"qa4mre_2013": {"acc": 0.18309859154929578, "acc_norm": 0.22183098591549297, "acc_norm_stderr": 0.02469760575535269, "acc_stderr": 0.022989742475464973}}, "versions": {"qa4mre_2013": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/qnli-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/qnli-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..883202c385fdfcbdb3e362737691ee0343adc430
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/qnli-v0-loglikelihood
@@ -0,0 +1 @@
+4281d4ff5cf1244358b0ea0220c67863c69fbade850696b43e8ff05138e01e12
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/qnli-v0-res.json b/lm-evaluation-harness/tests/testdata/qnli-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..31c3097605f33c489d4f2552ce3060cd7a9155e3
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/qnli-v0-res.json
@@ -0,0 +1 @@
+{"results": {"qnli": {"acc": 0.5108914515833791, "acc_stderr": 0.00676380528502966}}, "versions": {"qnli": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/qqp-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/qqp-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..ecc86dc396332c1aaa8e638e5413633a504e7206
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/qqp-v0-loglikelihood
@@ -0,0 +1 @@
+97b551b0fc3d239aad4929a2e8e79c986891aefd9fcd19441fea0382d507889e
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/qqp-v0-res.json b/lm-evaluation-harness/tests/testdata/qqp-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..b7b31355e644bd9d6d57758ee9a454598445f7c9
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/qqp-v0-res.json
@@ -0,0 +1 @@
+{"results": {"qqp": {"acc": 0.49782339846648527, "acc_stderr": 0.0024866770696239894, "f1": 0.42322661288031593, "f1_stderr": 0.002695903831328166}}, "versions": {"qqp": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/race-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/race-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..5fe1ce356b49f558ce758de50809109acd9c153c
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/race-v0-loglikelihood
@@ -0,0 +1 @@
+bdfdfab7fa1c7af0c1e161785e347b1b8071a15cbf971f6f2a9ae8c8e845199f
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/race-v0-res.json b/lm-evaluation-harness/tests/testdata/race-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..017b00669b8b60dc06947e4e78428fb429734df5
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/race-v0-res.json
@@ -0,0 +1 @@
+{"results": {"race": {"acc": 0.23253588516746412, "acc_stderr": 0.013074460615265295}}, "versions": {"race": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/random_insertion-v0-greedy_until b/lm-evaluation-harness/tests/testdata/random_insertion-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..4844e5393b8358d225f516f1a948f1deccab7840
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/random_insertion-v0-greedy_until
@@ -0,0 +1 @@
+6c48baa6924f3635120f33062251c4b571b3d4e9fe46b14d91f54ddd1c857997
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/random_insertion-v0-res.json b/lm-evaluation-harness/tests/testdata/random_insertion-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..9b5f507f6745120414ba5cfd39fc92eac4e48424
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/random_insertion-v0-res.json
@@ -0,0 +1 @@
+{"results": {"random_insertion": {"acc": 0.0, "acc_stderr": 0.0}}, "versions": {"random_insertion": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/record-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/record-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..a54fa05cd1ac551a973ff8155ddca6d868a49b42
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/record-v0-loglikelihood
@@ -0,0 +1 @@
+a3e378fbde4e28f375cac1561bbfc7d7673c2af193628a774ad012d5192393aa
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/record-v0-res.json b/lm-evaluation-harness/tests/testdata/record-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..006c381372178097b36bfac48795e6fbdc242b1a
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/record-v0-res.json
@@ -0,0 +1 @@
+{"results": {"record": {"em": 0.1521, "em_stderr": 0.0035913575128186616, "f1": 0.1581870634920636, "f1_stderr": 0.0036146895141474576}}, "versions": {"record": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/reversed_words-v0-greedy_until b/lm-evaluation-harness/tests/testdata/reversed_words-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..3f28488a9028fed32a088de9a2e8c0fac4fd12de
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/reversed_words-v0-greedy_until
@@ -0,0 +1 @@
+1d79fc4f0177f9624a487b9973f4e0e1d3f8404993b419a7b807a690ebbbb290
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/reversed_words-v0-res.json b/lm-evaluation-harness/tests/testdata/reversed_words-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..9285ff2694c140b120aca438098daa39fc282a87
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/reversed_words-v0-res.json
@@ -0,0 +1 @@
+{"results": {"reversed_words": {"acc": 0.0, "acc_stderr": 0.0}}, "versions": {"reversed_words": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/rte-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/rte-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..c239923e4f3ec676961da50b3823c09872edd36d
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/rte-v0-loglikelihood
@@ -0,0 +1 @@
+c80ce13c8c736087f1557f8736d5d318b540ff01e4bb7f55e568890dc8b0393e
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/rte-v0-res.json b/lm-evaluation-harness/tests/testdata/rte-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..10314dd047e4d7202c755fe8cfc55bc9b1edd5f8
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/rte-v0-res.json
@@ -0,0 +1 @@
+{"results": {"rte": {"acc": 0.5379061371841155, "acc_stderr": 0.030009848912529117}}, "versions": {"rte": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/sciq-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/sciq-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..25ce988773df6dd27009a4ac47357dfb7d70748e
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/sciq-v0-loglikelihood
@@ -0,0 +1 @@
+71cbb6e2a7ac4512c3761ea801d420eb3fac49d158c7e4deaa3ab8727bea923c
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/sciq-v0-res.json b/lm-evaluation-harness/tests/testdata/sciq-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..7071515827af18b10a7b3607e6249ed3e7c1929e
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/sciq-v0-res.json
@@ -0,0 +1 @@
+{"results": {"sciq": {"acc": 0.234, "acc_norm": 0.239, "acc_norm_stderr": 0.01349300044693758, "acc_stderr": 0.01339490288966001}}, "versions": {"sciq": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/squad2-v0-greedy_until b/lm-evaluation-harness/tests/testdata/squad2-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..024652e0a39ed0298f8f6f67453f644a68f3a367
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/squad2-v0-greedy_until
@@ -0,0 +1 @@
+b261e8885c11750ce6911bb11e8693de03d53758297c26fb14cfc1ef508862cb
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/squad2-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/squad2-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..41300bc19fd3142bfd547bf21f2b28b3ce5b21c9
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/squad2-v0-loglikelihood
@@ -0,0 +1 @@
+287e87cc6878debcc80d9b6df4e2d0a74ed29068e0e0a80906c8441843a17cee
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/squad2-v0-res.json b/lm-evaluation-harness/tests/testdata/squad2-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..2b370553acca14706a39428146194fa9449e09f2
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/squad2-v0-res.json
@@ -0,0 +1 @@
+{"results": {"squad2": {"HasAns_exact": 0.0, "HasAns_f1": 0.0, "NoAns_exact": 0.0, "NoAns_f1": 0.0, "best_exact": 50.07159100480081, "best_f1": 50.07159100480081, "exact": 0.0, "f1": 0.0}}, "versions": {"squad2": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/squad2-v1-greedy_until b/lm-evaluation-harness/tests/testdata/squad2-v1-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..70df2fd6ae1f59de5b6f3f6712bc2331197400c8
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/squad2-v1-greedy_until
@@ -0,0 +1 @@
+e17e3d85c1d5adaf2d6b4b752c4babc2e0b3a6e144e6de70cb3b2287e85109b8
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/squad2-v1-loglikelihood b/lm-evaluation-harness/tests/testdata/squad2-v1-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..2c970f7583b3d8236d9ca2e802ce6e0403b36074
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/squad2-v1-loglikelihood
@@ -0,0 +1 @@
+f5da6173402b274dc89130755c222c6ca6b2a3bacaaa4e4ab07be9322b7bad65
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/squad2-v1-res.json b/lm-evaluation-harness/tests/testdata/squad2-v1-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..dd69f00abb989ba3d254b9a6925087e10737b8d6
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/squad2-v1-res.json
@@ -0,0 +1 @@
+{"results": {"squad2": {"HasAns_exact": 0.0, "HasAns_f1": 0.0, "NoAns_exact": 0.0, "NoAns_f1": 0.0, "best_exact": 50.07159100480081, "best_f1": 50.07159100480081, "exact": 0.0, "f1": 0.0}}, "versions": {"squad2": 1}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/sst-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/sst-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..52050de16b54b432bdd68fae780660a035b10c0a
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/sst-v0-loglikelihood
@@ -0,0 +1 @@
+d2ebe3a63517d1d481aa1513bebe124c57a0904554a1e95f566979cfe67b1a7f
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/sst-v0-res.json b/lm-evaluation-harness/tests/testdata/sst-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..5fe3c62a205cdd7a57acaf082f671e9ba864e5f7
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/sst-v0-res.json
@@ -0,0 +1 @@
+{"results": {"sst": {"acc": 0.5172018348623854, "acc_stderr": 0.016931824425903734}}, "versions": {"sst": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/swag-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/swag-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..c8152027dc2f15319676bc32d55f32ca0bec00b5
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/swag-v0-loglikelihood
@@ -0,0 +1 @@
+be4fcbad876124c4ba3c71970538a97fec0e36a9cc677c70b6c9243a7bcee0ec
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/swag-v0-res.json b/lm-evaluation-harness/tests/testdata/swag-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..a1aeee972e83a41dbb7301f5a98ad5c97486402f
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/swag-v0-res.json
@@ -0,0 +1 @@
+{"results": {"swag": {"acc": 0.2482255323402979, "acc_norm": 0.24882535239428172, "acc_norm_stderr": 0.00305666959496067, "acc_stderr": 0.003054201832644171}}, "versions": {"swag": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/toxigen-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/toxigen-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..3074e09e14cf0763aa58e8fe2801337da805b734
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/toxigen-v0-loglikelihood
@@ -0,0 +1 @@
+7fedd930bafa92b9cca615a93ba92a4413244d2b77cf3f421a186815d721e0fa
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/toxigen-v0-res.json b/lm-evaluation-harness/tests/testdata/toxigen-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..65bb7cf4596c8973ae7dd2efc60e366c65bc4800
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/toxigen-v0-res.json
@@ -0,0 +1 @@
+{"results": {"toxigen": {"acc": 0.5053191489361702, "acc_norm": 0.46808510638297873, "acc_norm_stderr": 0.016283609940023203, "acc_stderr": 0.016315959984563776}}, "versions": {"toxigen": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/triviaqa-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/triviaqa-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..d576c4977fc769dc56c31340f07558fefc1f1459
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/triviaqa-v0-loglikelihood
@@ -0,0 +1 @@
+f8ec05b306b9f6187c0f8117cae441fb85a7a2e4670f4f9a1a3b632b1978421a
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/triviaqa-v0-res.json b/lm-evaluation-harness/tests/testdata/triviaqa-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..ab98847da6985f5c9d1e650008367ba739a1147f
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/triviaqa-v0-res.json
@@ -0,0 +1 @@
+{"results": {"triviaqa": {"acc": 0.0, "acc_stderr": 0.0}}, "versions": {"triviaqa": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/triviaqa-v1-loglikelihood b/lm-evaluation-harness/tests/testdata/triviaqa-v1-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..d576c4977fc769dc56c31340f07558fefc1f1459
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/triviaqa-v1-loglikelihood
@@ -0,0 +1 @@
+f8ec05b306b9f6187c0f8117cae441fb85a7a2e4670f4f9a1a3b632b1978421a
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/triviaqa-v1-res.json b/lm-evaluation-harness/tests/testdata/triviaqa-v1-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..985f64c8e0eb3bc1dd563becf0cdf186baa172cd
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/triviaqa-v1-res.json
@@ -0,0 +1 @@
+{"results": {"triviaqa": {"acc": 0.0, "acc_stderr": 0.0}}, "versions": {"triviaqa": 1}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/truthfulqa_gen-v0-greedy_until b/lm-evaluation-harness/tests/testdata/truthfulqa_gen-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..52156c85072e4f1a829345a4b9eef7af2c2ca059
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/truthfulqa_gen-v0-greedy_until
@@ -0,0 +1 @@
+0d7c56e1aa71ffd8f94bde28f6e8dfdd35f7aaadffa0620bd2a27704253d6c14
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/truthfulqa_gen-v0-res.json b/lm-evaluation-harness/tests/testdata/truthfulqa_gen-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..5e68fa8dc6ace5fd91322aacdc74de3814832d9a
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/truthfulqa_gen-v0-res.json
@@ -0,0 +1 @@
+{"results": {"truthfulqa_gen": {"bleu_acc": 0.0, "bleu_acc_stderr": 0.0, "bleu_diff": 0.0, "bleu_diff_stderr": 0.0, "bleu_max": 0.0, "bleu_max_stderr": 0.0, "bleurt_acc": 0.8372093023255814, "bleurt_acc_stderr": 0.012923696051772253, "bleurt_diff": 0.13967358205134603, "bleurt_diff_stderr": 0.00532907098769571, "bleurt_max": -1.4402793981454072, "bleurt_max_stderr": 0.0021884846359458963, "rouge1_acc": 0.0, "rouge1_acc_stderr": 0.0, "rouge1_diff": 0.0, "rouge1_diff_stderr": 0.0, "rouge1_max": 0.0, "rouge1_max_stderr": 0.0, "rouge2_acc": 0.0, "rouge2_acc_stderr": 0.0, "rouge2_diff": 0.0, "rouge2_diff_stderr": 0.0, "rouge2_max": 0.0, "rouge2_max_stderr": 0.0, "rougeL_acc": 0.0, "rougeL_acc_stderr": 0.0, "rougeL_diff": 0.0, "rougeL_diff_stderr": 0.0, "rougeL_max": 0.0, "rougeL_max_stderr": 0.0}}, "versions": {"truthfulqa_gen": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/truthfulqa_gen-v1-greedy_until b/lm-evaluation-harness/tests/testdata/truthfulqa_gen-v1-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..d5261f22133a65b6968881eeb87260c5a1fca3af
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/truthfulqa_gen-v1-greedy_until
@@ -0,0 +1 @@
+1a280973bbac2b7ac29dd64dddac474fb4749585f7de893483b4034814466c67
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/truthfulqa_gen-v1-res.json b/lm-evaluation-harness/tests/testdata/truthfulqa_gen-v1-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..30aa72f2bafd0788837ca50fa9d5c75f954daef0
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/truthfulqa_gen-v1-res.json
@@ -0,0 +1 @@
+{"results": {"truthfulqa_gen": {"bleu_acc": 0.0, "bleu_acc_stderr": 0.0, "bleu_diff": 0.0, "bleu_diff_stderr": 0.0, "bleu_max": 0.0, "bleu_max_stderr": 0.0, "bleurt_acc": 0.835985312117503, "bleurt_acc_stderr": 0.012962704327492454, "bleurt_diff": 0.14077322143090107, "bleurt_diff_stderr": 0.005459888909582694, "bleurt_max": -1.4399358725752065, "bleurt_max_stderr": 0.0022126992369197133, "rouge1_acc": 0.0, "rouge1_acc_stderr": 0.0, "rouge1_diff": 0.0, "rouge1_diff_stderr": 0.0, "rouge1_max": 0.0, "rouge1_max_stderr": 0.0, "rouge2_acc": 0.0, "rouge2_acc_stderr": 0.0, "rouge2_diff": 0.0, "rouge2_diff_stderr": 0.0, "rouge2_max": 0.0, "rouge2_max_stderr": 0.0, "rougeL_acc": 0.0, "rougeL_acc_stderr": 0.0, "rougeL_diff": 0.0, "rougeL_diff_stderr": 0.0, "rougeL_max": 0.0, "rougeL_max_stderr": 0.0}}, "versions": {"truthfulqa_gen": 1}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/truthfulqa_mc-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/truthfulqa_mc-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..51303977a9cbb311433a840af6ce636728bdb118
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/truthfulqa_mc-v0-loglikelihood
@@ -0,0 +1 @@
+226a6783976177dc9ceda5688623ff37023242eff30ddf270b886bf7b9b32228
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/truthfulqa_mc-v0-res.json b/lm-evaluation-harness/tests/testdata/truthfulqa_mc-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..b12b4765cce2e95398697685a9ebb0cdada833bf
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/truthfulqa_mc-v0-res.json
@@ -0,0 +1 @@
+{"results": {"truthfulqa_mc": {"mc1": 0.2141982864137087, "mc1_stderr": 0.01436214815569045, "mc2": 0.465436996173817, "mc2_stderr": 0.0048422530880316405}}, "versions": {"truthfulqa_mc": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/truthfulqa_mc-v1-loglikelihood b/lm-evaluation-harness/tests/testdata/truthfulqa_mc-v1-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..4bab2d1f4df241fe0cf47f22bf185d52f9b783ef
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/truthfulqa_mc-v1-loglikelihood
@@ -0,0 +1 @@
+1e07020e9cf41d46ed65312eb39d2b8e6599673d4f0d6b67c0d0eba0efb493bb
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/truthfulqa_mc-v1-res.json b/lm-evaluation-harness/tests/testdata/truthfulqa_mc-v1-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..c1b1854c2e0abc9c4fe8096b4d45004bcc1a381b
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/truthfulqa_mc-v1-res.json
@@ -0,0 +1 @@
+{"results": {"truthfulqa_mc": {"mc1": 0.23255813953488372, "mc1_stderr": 0.01478915753108052, "mc2": 0.4462325560722362, "mc2_stderr": 0.004986523944692003}}, "versions": {"truthfulqa_mc": 1}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/webqs-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/webqs-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..4d604d438db6c4cc77a43aca8d2a7f605aef6b1c
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/webqs-v0-loglikelihood
@@ -0,0 +1 @@
+96b218173468cc94552a0b946193bda89faba51f1bfc3e7945531f9dff8d6fe9
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-cs-en-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-cs-en-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..70c80afe5bd10baabdcb507faa385db124c1f42e
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-cs-en-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-cs-en": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 0.006212086270964023, "chrf_stderr": 0.0001119165191795531, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-cs-en": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-en-ja-v1-res.json b/lm-evaluation-harness/tests/testdata/wmt20-en-ja-v1-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..be5e56abcf2253276d405dae64758b9cab09f3e4
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-en-ja-v1-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-en-ja": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 4.1305928226819116e-05, "chrf_stderr": 2.0455354158878388e-05, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-en-ja": 1}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-en-km-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-en-km-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..e5ee2e9be911cda88b6445715b833e1a0dbf92dd
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-en-km-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-en-km": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 1.9008351315007364e-05, "chrf_stderr": 7.136657625458525e-06, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-en-km": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-en-pl-v0-greedy_until b/lm-evaluation-harness/tests/testdata/wmt20-en-pl-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..bd431d61c479beb686d39be21905fdb0beb7781e
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-en-pl-v0-greedy_until
@@ -0,0 +1 @@
+952f02575d4936d93c4d2808d86c4bf5f1f3a0901212acee6cbc1f9cbd30d39e
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-en-pl-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-en-pl-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..13bfd5b552b92b771266666dd5fe5b9496064051
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-en-pl-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-en-pl": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 0.009006977773147825, "chrf_stderr": 0.00023387733367766675, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-en-pl": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-en-ps-v0-greedy_until b/lm-evaluation-harness/tests/testdata/wmt20-en-ps-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..77b600c49afa12cf988280e337a9d4747195f95f
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-en-ps-v0-greedy_until
@@ -0,0 +1 @@
+8411c2cb73114cbd0c6e0f17eab2625d486cc3a601105deb0ea1338a401df689
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-en-ps-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-en-ps-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..fcfb51f05320490d089cc8fbd4127a987bc868c0
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-en-ps-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-en-ps": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 2.1193813610582323e-06, "chrf_stderr": 2.113911466119111e-06, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-en-ps": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-en-ru-v0-greedy_until b/lm-evaluation-harness/tests/testdata/wmt20-en-ru-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..d21d39ac9f9616bda1e21d1ba5bd63fdb542a7aa
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-en-ru-v0-greedy_until
@@ -0,0 +1 @@
+a1613831f69c1679a54670092af40ce76617b79d7cc837984803b0fc52bb8bde
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-en-ru-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-en-ru-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..af339eda5d3d76e00e3e0f3c800353bb2b7fb696
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-en-ru-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-en-ru": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 0.0007327811114614671, "chrf_stderr": 4.43155903515048e-05, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-en-ru": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-en-ta-v0-greedy_until b/lm-evaluation-harness/tests/testdata/wmt20-en-ta-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..1b40263f154461098d6ee820bc0d003c03a6962c
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-en-ta-v0-greedy_until
@@ -0,0 +1 @@
+5fc556fa90bca7f1b1396e97e392eac8080b0ad53488358799b8fc0b21a94cb1
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-en-ta-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-en-ta-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..b04f968d76055c494762ec6cd2a84327c8351742
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-en-ta-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-en-ta": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 0.0, "chrf_stderr": 0.0, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-en-ta": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-en-zh-v0-greedy_until b/lm-evaluation-harness/tests/testdata/wmt20-en-zh-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..db79b7f03fcfc8f7720f1344339e7d94d8a01ebf
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-en-zh-v0-greedy_until
@@ -0,0 +1 @@
+67f0333ddbcb07d7a9ac12919129a18fe4fea24e4826a11bbdde4fd5ed5ed83f
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-en-zh-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-en-zh-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..24db35e62fd176b0454ff426ab749787da805897
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-en-zh-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-en-zh": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 0.00014170297316825535, "chrf_stderr": 6.590669847391838e-05, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-en-zh": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-en-zh-v1-greedy_until b/lm-evaluation-harness/tests/testdata/wmt20-en-zh-v1-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..db79b7f03fcfc8f7720f1344339e7d94d8a01ebf
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-en-zh-v1-greedy_until
@@ -0,0 +1 @@
+67f0333ddbcb07d7a9ac12919129a18fe4fea24e4826a11bbdde4fd5ed5ed83f
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-en-zh-v1-res.json b/lm-evaluation-harness/tests/testdata/wmt20-en-zh-v1-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..a7a56daf0e793acf229c9b16a751383473bd5e26
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-en-zh-v1-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-en-zh": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 0.00014170297316825535, "chrf_stderr": 6.590669847391838e-05, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-en-zh": 1}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-fr-de-v0-greedy_until b/lm-evaluation-harness/tests/testdata/wmt20-fr-de-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..7353ad4475b3d292bfd64e6dcb41972d697c34da
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-fr-de-v0-greedy_until
@@ -0,0 +1 @@
+8a4b65c59dcac6591d46261909ee92ebcf41c19ee7442b12842302b2d8aeb36f
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-fr-de-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-fr-de-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..d5d06a02a30635ad57907b32ae66ccb9ba5a7e23
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-fr-de-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-fr-de": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 0.01143193767396364, "chrf_stderr": 0.00012555271954563658, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-fr-de": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-iu-en-v0-greedy_until b/lm-evaluation-harness/tests/testdata/wmt20-iu-en-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..87a1981e79e0558366487aa2476cc751ad3857dc
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-iu-en-v0-greedy_until
@@ -0,0 +1 @@
+97bf664a8efa54b5366b8341f77b418106dd0cb26169d5b2d0144e4d3d2bc5c9
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-iu-en-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-iu-en-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..e94cac8876d9d04c883b5ad5810884af7faa436c
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-iu-en-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-iu-en": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 0.012204628007572778, "chrf_stderr": 8.944407532175802e-05, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-iu-en": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-ja-en-v0-greedy_until b/lm-evaluation-harness/tests/testdata/wmt20-ja-en-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..3a89d7fcdfb76bc3912a930cf592da0270ba440c
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-ja-en-v0-greedy_until
@@ -0,0 +1 @@
+1fd846f3c0104e794eb380dae7f648592092ab8bf59234c26d0a671bbbc28df1
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-ja-en-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-ja-en-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..4344b7cd8a1a9bfb8cd60e2aa0ece17f530f7d3d
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-ja-en-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-ja-en": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 0.010703148854351403, "chrf_stderr": 0.00022242113108130186, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-ja-en": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-km-en-v0-greedy_until b/lm-evaluation-harness/tests/testdata/wmt20-km-en-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..a6f148661093f5f97c85e96ab2c01da6e40c1547
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-km-en-v0-greedy_until
@@ -0,0 +1 @@
+fb4ec81bb89c70df7e21b43e0e882915b7b71a2a85bb8d4b59e0c7938baaa4c2
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-km-en-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-km-en-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..4f6dc98604bdeed7b87806094a6ffc3b0cbbfec4
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-km-en-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-km-en": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 0.015142474534585969, "chrf_stderr": 0.0001518735048829897, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-km-en": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-pl-en-v0-greedy_until b/lm-evaluation-harness/tests/testdata/wmt20-pl-en-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..899ce01919910ab80fc95b99371bf334a7c7c37a
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-pl-en-v0-greedy_until
@@ -0,0 +1 @@
+89274499d84176b1ffe4eaec06f2c89ca807342384dc946c2e348d00116aaade
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-pl-en-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-pl-en-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..a2f5cb31be388a5ca081567e72d16e42774aa008
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-pl-en-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-pl-en": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 0.01353367757716276, "chrf_stderr": 0.00018386199249976465, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-pl-en": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-ps-en-v0-greedy_until b/lm-evaluation-harness/tests/testdata/wmt20-ps-en-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..7776c5952383a6254943869dad8fddb50e50e987
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-ps-en-v0-greedy_until
@@ -0,0 +1 @@
+c3976465e3709b4bc371175cc1494c69fe096ea4ba7d114da779d2baa0a47466
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-ps-en-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-ps-en-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..00c9c742e4d34830628a52aa34cfd7faaa86516c
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-ps-en-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-ps-en": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 0.015192865365105723, "chrf_stderr": 0.00011334541381539086, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-ps-en": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-ru-en-v0-greedy_until b/lm-evaluation-harness/tests/testdata/wmt20-ru-en-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..27c60fb72194325e51647ce0fe137710df6dff86
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-ru-en-v0-greedy_until
@@ -0,0 +1 @@
+1477ab6542c26bd0222cc1aded174f33bf8d04d1cf6a1c0959aeca4ff3779adc
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-ru-en-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-ru-en-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..b6d0c71ad7c140790040022c51970dea075ab0b1
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-ru-en-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-ru-en": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 0.013344639906399232, "chrf_stderr": 7.583552652374546e-05, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-ru-en": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-ta-en-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-ta-en-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..a2ad506bf94188b54a0f3b7ee6f5d787d34e68ff
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-ta-en-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-ta-en": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 0.013841110664859798, "chrf_stderr": 0.00018476696850880766, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-ta-en": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-zh-en-v0-greedy_until b/lm-evaluation-harness/tests/testdata/wmt20-zh-en-v0-greedy_until
new file mode 100644
index 0000000000000000000000000000000000000000..41a1e91515b30a2acdc6363c36af1cdf43f477a9
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-zh-en-v0-greedy_until
@@ -0,0 +1 @@
+07dbadfd6f2b2b9462ab6187dbfaabae6e5192ab89a8e4ede9237834b9364dd1
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wmt20-zh-en-v0-res.json b/lm-evaluation-harness/tests/testdata/wmt20-zh-en-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..11b8df7f8739d9e4a459636640af6ebb2b7b868a
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wmt20-zh-en-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wmt20-zh-en": {"bleu": 0.0, "bleu_stderr": 0.0, "chrf": 0.008438201290981157, "chrf_stderr": 0.0001109053964076822, "ter": 1.0, "ter_stderr": 0.0}}, "versions": {"wmt20-zh-en": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wnli-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/wnli-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..0c5c0b8ceb64a158bd57294d432b2186f3a0fdf9
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wnli-v0-loglikelihood
@@ -0,0 +1 @@
+2ffd304d6096416eb29607e2e7642b1d6043163624967bcf4c4fc00fddc6c721
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wnli-v0-res.json b/lm-evaluation-harness/tests/testdata/wnli-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..8841cb74d16977645c1c7399d8b58de094bafef1
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wnli-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wnli": {"acc": 0.3380281690140845, "acc_stderr": 0.05653887739133514}}, "versions": {"wnli": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wnli-v1-loglikelihood b/lm-evaluation-harness/tests/testdata/wnli-v1-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..cbf4ad3777eebbcee7c1ccf1c4a4cac64829ad2b
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wnli-v1-loglikelihood
@@ -0,0 +1 @@
+8a0f81661d2ab2334bbc8031fac31c0c8882f1d9271dd51599d21dfdbb726dea
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wnli-v1-res.json b/lm-evaluation-harness/tests/testdata/wnli-v1-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..d12348e0aeb8d7feec272059e08eb30cbb1d918d
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wnli-v1-res.json
@@ -0,0 +1 @@
+{"results": {"wnli": {"acc": 0.5633802816901409, "acc_stderr": 0.0592793555841297}}, "versions": {"wnli": 1}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wsc-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/wsc-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..d0d2963fe90b29dbbf2527e9a3b559cf9b9c23c7
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wsc-v0-loglikelihood
@@ -0,0 +1 @@
+45865468eff5ca31e6a050947a6b3310d9d5ed19d0f2e578a32ecaf1c768600f
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wsc-v0-res.json b/lm-evaluation-harness/tests/testdata/wsc-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..84be59624161779e494896d2618dbcf0f1f4b4b0
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wsc-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wsc": {"acc": 0.5480769230769231, "acc_stderr": 0.049038186969314335}}, "versions": {"wsc": 0}}
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wsc273-v0-loglikelihood b/lm-evaluation-harness/tests/testdata/wsc273-v0-loglikelihood
new file mode 100644
index 0000000000000000000000000000000000000000..9d592917bd96783c290237446891eef56083a693
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wsc273-v0-loglikelihood
@@ -0,0 +1 @@
+26450d414c4581feb51a09882080e7a9b95882e7eab47b1751a4a6024b5a60ee
\ No newline at end of file
diff --git a/lm-evaluation-harness/tests/testdata/wsc273-v0-res.json b/lm-evaluation-harness/tests/testdata/wsc273-v0-res.json
new file mode 100644
index 0000000000000000000000000000000000000000..8f023b422a7003d2984e35e58045d8866954a4c4
--- /dev/null
+++ b/lm-evaluation-harness/tests/testdata/wsc273-v0-res.json
@@ -0,0 +1 @@
+{"results": {"wsc273": {"acc": 0.5164835164835165, "acc_stderr": 0.0303004740355766}}, "versions": {"wsc273": 0}}
\ No newline at end of file
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/.github/ISSUE_TEMPLATE/bug_report.md b/lm-quant-toolkit/.deps/AutoGPTQ/.github/ISSUE_TEMPLATE/bug_report.md
new file mode 100644
index 0000000000000000000000000000000000000000..d047af6e8e361b71bb7a5b915a8c9cff4f00f1e9
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/.github/ISSUE_TEMPLATE/bug_report.md
@@ -0,0 +1,33 @@
+---
+name: Bug report
+about: Create a report to help us improve
+title: "[BUG]"
+labels: bug
+assignees: ''
+
+---
+
+**Describe the bug**
+A clear and concise description of what the bug is.
+
+**Hardware details**
+Information about CPU and GPU, such as RAM, number, etc.
+
+**Software version**
+Version of relevant software such as operation system, cuda toolkit, python, auto-gptq, pytorch, transformers, accelerate, etc.
+
+**To Reproduce**
+Steps to reproduce the behavior:
+1. Go to '...'
+2. Click on '....'
+3. Scroll down to '....'
+4. See error
+
+**Expected behavior**
+A clear and concise description of what you expected to happen.
+
+**Screenshots**
+If applicable, add screenshots to help explain your problem.
+
+**Additional context**
+Add any other context about the problem here.
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/.github/ISSUE_TEMPLATE/custom.md b/lm-quant-toolkit/.deps/AutoGPTQ/.github/ISSUE_TEMPLATE/custom.md
new file mode 100644
index 0000000000000000000000000000000000000000..48d5f81fa422964dd1eea360efdecfc5dc9a6c87
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/.github/ISSUE_TEMPLATE/custom.md
@@ -0,0 +1,10 @@
+---
+name: Custom issue template
+about: Describe this issue template's purpose here.
+title: ''
+labels: ''
+assignees: ''
+
+---
+
+
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/.github/ISSUE_TEMPLATE/feature_request.md b/lm-quant-toolkit/.deps/AutoGPTQ/.github/ISSUE_TEMPLATE/feature_request.md
new file mode 100644
index 0000000000000000000000000000000000000000..f45586549c215746dd615f3b3a36518386097dc1
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/.github/ISSUE_TEMPLATE/feature_request.md
@@ -0,0 +1,20 @@
+---
+name: Feature request
+about: Suggest an idea for this project
+title: "[FEATURE]"
+labels: enhancement
+assignees: ''
+
+---
+
+**Is your feature request related to a problem? Please describe.**
+A clear and concise description of what the problem is. Ex. I'm always frustrated when [...]
+
+**Describe the solution you'd like**
+A clear and concise description of what you want to happen.
+
+**Describe alternatives you've considered**
+A clear and concise description of any alternative solutions or features you've considered.
+
+**Additional context**
+Add any other context or screenshots about the feature request here.
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/build_wheels_cuda_linux.yml b/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/build_wheels_cuda_linux.yml
new file mode 100644
index 0000000000000000000000000000000000000000..39b0ed0d7e6ba157c6c061019e81e9d3e114071b
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/build_wheels_cuda_linux.yml
@@ -0,0 +1,115 @@
+name: Build AutoGPTQ Wheels with CUDA for Linux
+
+on: workflow_dispatch
+
+jobs:
+ build_wheels:
+ if: ${{ github.repository_owner == 'AutoGPTQ' }}
+ name: Build wheels for ${{ matrix.os }} and Python ${{ matrix.python }} and CUDA ${{ matrix.cuda }}
+ runs-on: ${{ matrix.os }}
+ strategy:
+ matrix:
+ os: [ubuntu-20.04]
+ pyver: ["3.8", "3.9", "3.10", "3.11"]
+ cuda: ["11.8"] # wheel for 12.1 are built in build_wheels_pypi.yml
+ defaults:
+ run:
+ shell: bash
+ env:
+ CUDA_VERSION: ${{ matrix.cuda }}
+
+ steps:
+ - uses: actions/checkout@v3
+
+ - name: Free disk space
+ run: |
+ # Go from 19G to 54G free disk space in 3min
+ df -h
+ sudo apt-get update
+ sudo apt-get purge -y '^apache.*'
+ sudo apt-get purge -y '^imagemagick.*'
+ sudo apt-get purge -y '^dotnet.*'
+ sudo apt-get purge -y '^aspnetcore.*'
+ sudo apt-get purge -y 'php.*'
+ sudo apt-get purge -y '^temurin.*'
+ sudo apt-get purge -y '^mysql.*'
+ sudo apt-get purge -y '^java.*'
+ sudo apt-get purge -y '^openjdk.*'
+ sudo apt-get purge -y microsoft-edge-stable google-cloud-cli azure-cli google-chrome-stable firefox powershell mono-devel
+ df -h
+ sudo apt-get autoremove -y >/dev/null 2>&1
+ sudo apt-get clean
+ df -h
+ echo "https://github.com/actions/virtual-environments/issues/709"
+ sudo rm -rf "$AGENT_TOOLSDIRECTORY"
+ df -h
+ echo "remove big /usr/local"
+ sudo rm -rf "/usr/local/share/boost"
+ sudo rm -rf /usr/local/lib/android >/dev/null 2>&1
+ df -h
+ echo "remove /usr/share leftovers"
+ sudo rm -rf /usr/share/dotnet/sdk > /dev/null 2>&1
+ sudo rm -rf /usr/share/dotnet/shared > /dev/null 2>&1
+ sudo rm -rf /usr/share/swift > /dev/null 2>&1
+ df -h
+ echo "remove other leftovers"
+ sudo rm -rf /var/lib/mysql > /dev/null 2>&1
+ sudo rm -rf /home/runner/.dotnet > /dev/null 2>&1
+ sudo rm -rf /home/runneradmin/.dotnet > /dev/null 2>&1
+ sudo rm -rf /etc/skel/.dotnet > /dev/null 2>&1
+ sudo rm -rf /usr/local/.ghcup > /dev/null 2>&1
+ sudo rm -rf /usr/local/aws-cli > /dev/null 2>&1
+ sudo rm -rf /usr/local/lib/node_modules > /dev/null 2>&1
+ sudo rm -rf /usr/lib/heroku > /dev/null 2>&1
+ sudo rm -rf /usr/local/share/chromium > /dev/null 2>&1
+ df -h
+
+ - uses: actions/setup-python@v3
+ with:
+ python-version: ${{ matrix.pyver }}
+
+ - name: Setup Miniconda
+ uses: conda-incubator/setup-miniconda@v2.2.0
+ with:
+ activate-environment: "build"
+ python-version: ${{ matrix.pyver }}
+ mamba-version: "*"
+ use-mamba: false
+ channels: conda-forge,defaults
+ channel-priority: true
+ add-pip-as-python-dependency: true
+ auto-activate-base: false
+
+ - name: Install Dependencies
+ run: |
+ conda install cuda-toolkit -c "nvidia/label/cuda-${CUDA_VERSION}.0"
+
+ # Refer to https://pytorch.org/get-started/locally/
+ python -m pip install torch --index-url https://download.pytorch.org/whl/cu118
+ python -m pip install --upgrade build setuptools wheel ninja numpy gekko pandas
+
+ - name: Check install
+ run: |
+ python -c "import torch; print('torch version:', torch.__version__)"
+
+ - name: Build Wheel
+ run: |
+ # For some reason $CONDA_PREFIX is empty.
+ export CUDA_HOME=/usr/share/miniconda
+ export CUDA_PATH=/usr/share/miniconda
+ export LD_LIBRARY_PATH="${LD_LIBRARY_PATH}:${CONDA_PREFIX}/lib"
+
+ export TORCH_CUDA_ARCH_LIST="6.0 6.1 7.0 7.5 8.0 8.6 8.9 9.0+PTX"
+
+ echo "CUDA_PATH:"
+ echo $CUDA_PATH
+
+ echo "PYPI_RELEASE:"
+ echo $PYPI_RELEASE
+
+ python setup.py sdist bdist_wheel
+
+ - uses: actions/upload-artifact@v3
+ with:
+ name: 'linux-cuda-wheels'
+ path: ./dist/*.whl
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/build_wheels_cuda_windows.yml b/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/build_wheels_cuda_windows.yml
new file mode 100644
index 0000000000000000000000000000000000000000..d65fd5e74d90b91954d863a72f2bedc638b8d3c0
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/build_wheels_cuda_windows.yml
@@ -0,0 +1,64 @@
+name: Build AutoGPTQ Wheels with CUDA for Windows
+
+on: workflow_dispatch
+
+jobs:
+ build_wheels:
+ if: ${{ github.repository_owner == 'AutoGPTQ' }}
+ name: Build wheels for ${{ matrix.os }} and Python ${{ matrix.python }} and CUDA ${{ matrix.cuda }}
+ runs-on: ${{ matrix.os }}
+ strategy:
+ matrix:
+ os: [windows-latest]
+ pyver: ["3.8", "3.9", "3.10", "3.11"]
+ cuda: ["11.8"] # wheel for 12.1 are built in build_wheels_pypi.yml
+ defaults:
+ run:
+ shell: pwsh
+ env:
+ CUDA_VERSION: ${{ matrix.cuda }}
+
+ steps:
+ - uses: actions/checkout@v3
+
+ - uses: actions/setup-python@v3
+ with:
+ python-version: ${{ matrix.pyver }}
+
+ - name: Setup Miniconda
+ uses: conda-incubator/setup-miniconda@v2.2.0
+ with:
+ activate-environment: "build"
+ python-version: ${{ matrix.pyver }}
+ mamba-version: "*"
+ use-mamba: false
+ channels: conda-forge,defaults
+ channel-priority: true
+ add-pip-as-python-dependency: true
+ auto-activate-base: false
+
+ - name: Install Dependencies
+ run: |
+ conda install cuda-toolkit -c "nvidia/label/cuda-${env:CUDA_VERSION}.0"
+
+ # Refer to https://pytorch.org/get-started/locally/
+ python -m pip install torch --index-url https://download.pytorch.org/whl/cu118
+ python -m pip install --upgrade build setuptools wheel ninja numpy gekko pandas
+
+ - name: Check install
+ run: |
+ python -c "import torch; print('torch version:', torch.__version__)"
+
+ - name: Build Wheel
+ run: |
+ $env:CUDA_PATH = $env:CONDA_PREFIX
+ $env:CUDA_HOME = $env:CONDA_PREFIX
+
+ $env:TORCH_CUDA_ARCH_LIST = '6.0 6.1 7.0 7.5 8.0 8.6+PTX'
+ if ([decimal]$env:CUDA_VERSION -ge 11.8) { $env:TORCH_CUDA_ARCH_LIST = '6.0 6.1 7.0 7.5 8.0 8.6 8.9 9.0+PTX' }
+ python setup.py sdist bdist_wheel
+
+ - uses: actions/upload-artifact@v3
+ with:
+ name: 'windows-cuda-wheels'
+ path: ./dist/*.whl
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/build_wheels_pypi_linux.yml b/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/build_wheels_pypi_linux.yml
new file mode 100644
index 0000000000000000000000000000000000000000..29cd45ca8e3b7b892ede842425c4e63f042c3330
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/build_wheels_pypi_linux.yml
@@ -0,0 +1,116 @@
+name: Build AutoGPTQ Wheels for PyPI with CUDA for Linux
+
+on: workflow_dispatch
+
+jobs:
+ build_wheels:
+ if: ${{ github.repository_owner == 'AutoGPTQ' }}
+ name: Build wheels for ${{ matrix.os }} and Python ${{ matrix.python }} and CUDA 12.1
+ runs-on: ${{ matrix.os }}
+ strategy:
+ matrix:
+ os: [ubuntu-20.04]
+ pyver: ["3.8", "3.9", "3.10", "3.11"]
+ defaults:
+ run:
+ shell: bash
+ env:
+ CUDA_VERSION: "12.1"
+
+ steps:
+ - uses: actions/checkout@v3
+
+ - name: Free disk space
+ run: |
+ # Go from 19G to 54G free disk space in 3min
+ df -h
+ sudo apt-get update
+ sudo apt-get purge -y '^apache.*'
+ sudo apt-get purge -y '^imagemagick.*'
+ sudo apt-get purge -y '^dotnet.*'
+ sudo apt-get purge -y '^aspnetcore.*'
+ sudo apt-get purge -y 'php.*'
+ sudo apt-get purge -y '^temurin.*'
+ sudo apt-get purge -y '^mysql.*'
+ sudo apt-get purge -y '^java.*'
+ sudo apt-get purge -y '^openjdk.*'
+ sudo apt-get purge -y microsoft-edge-stable google-cloud-cli azure-cli google-chrome-stable firefox powershell mono-devel
+ df -h
+ sudo apt-get autoremove -y >/dev/null 2>&1
+ sudo apt-get clean
+ df -h
+ echo "https://github.com/actions/virtual-environments/issues/709"
+ sudo rm -rf "$AGENT_TOOLSDIRECTORY"
+ df -h
+ echo "remove big /usr/local"
+ sudo rm -rf "/usr/local/share/boost"
+ sudo rm -rf /usr/local/lib/android >/dev/null 2>&1
+ df -h
+ echo "remove /usr/share leftovers"
+ sudo rm -rf /usr/share/dotnet/sdk > /dev/null 2>&1
+ sudo rm -rf /usr/share/dotnet/shared > /dev/null 2>&1
+ sudo rm -rf /usr/share/swift > /dev/null 2>&1
+ df -h
+ echo "remove other leftovers"
+ sudo rm -rf /var/lib/mysql > /dev/null 2>&1
+ sudo rm -rf /home/runner/.dotnet > /dev/null 2>&1
+ sudo rm -rf /home/runneradmin/.dotnet > /dev/null 2>&1
+ sudo rm -rf /etc/skel/.dotnet > /dev/null 2>&1
+ sudo rm -rf /usr/local/.ghcup > /dev/null 2>&1
+ sudo rm -rf /usr/local/aws-cli > /dev/null 2>&1
+ sudo rm -rf /usr/local/lib/node_modules > /dev/null 2>&1
+ sudo rm -rf /usr/lib/heroku > /dev/null 2>&1
+ sudo rm -rf /usr/local/share/chromium > /dev/null 2>&1
+ df -h
+
+ - uses: actions/setup-python@v3
+ with:
+ python-version: ${{ matrix.pyver }}
+
+ - name: Setup Miniconda
+ uses: conda-incubator/setup-miniconda@v2.2.0
+ with:
+ activate-environment: "build"
+ python-version: ${{ matrix.pyver }}
+ mamba-version: "*"
+ use-mamba: false
+ channels: conda-forge,defaults
+ channel-priority: true
+ add-pip-as-python-dependency: true
+ auto-activate-base: false
+
+ - name: Install Dependencies
+ run: |
+ conda install cuda-toolkit -c "nvidia/label/cuda-${CUDA_VERSION}.0"
+
+ # Refer to https://pytorch.org/get-started/locally/
+ python -m pip install torch
+ python -m pip install --upgrade build setuptools wheel ninja numpy gekko pandas
+
+ - name: Check install
+ run: |
+ python -c "import torch; print('torch version:', torch.__version__)"
+
+ - name: Build Wheel
+ run: |
+ # For some reason $CONDA_PREFIX is empty.
+ export CUDA_HOME=/usr/share/miniconda
+ export CUDA_PATH=/usr/share/miniconda
+ export LD_LIBRARY_PATH="$LD_LIBRARY_PATH:${CONDA_PREFIX}/lib"
+
+ export TORCH_CUDA_ARCH_LIST="6.0 6.1 7.0 7.5 8.0 8.6 8.9 9.0+PTX"
+
+ export PYPI_RELEASE="1"
+
+ echo "CUDA_PATH:"
+ echo $CUDA_PATH
+
+ echo "PYPI_RELEASE:"
+ echo $PYPI_RELEASE
+
+ python setup.py sdist bdist_wheel
+
+ - uses: actions/upload-artifact@v3
+ with:
+ name: 'linux-cuda-wheels-pypi'
+ path: ./dist/*.whl
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/build_wheels_pypi_windows.yml b/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/build_wheels_pypi_windows.yml
new file mode 100644
index 0000000000000000000000000000000000000000..403e8eaba5423fca62018855c3e3947184b47d5c
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/build_wheels_pypi_windows.yml
@@ -0,0 +1,72 @@
+name: Build AutoGPTQ Wheels for PyPI with CUDA for Windows
+
+on: workflow_dispatch
+
+jobs:
+ build_wheels:
+ if: ${{ github.repository_owner == 'AutoGPTQ' }}
+ name: Build wheels for ${{ matrix.os }} and Python ${{ matrix.python }} and CUDA 12.1
+ runs-on: ${{ matrix.os }}
+ strategy:
+ matrix:
+ os: [windows-latest]
+ pyver: ["3.8", "3.9", "3.10", "3.11"]
+ defaults:
+ run:
+ shell: pwsh
+ env:
+ CUDA_VERSION: "12.1"
+
+ steps:
+ - uses: actions/checkout@v3
+
+ - uses: actions/setup-python@v3
+ with:
+ python-version: ${{ matrix.pyver }}
+
+ - name: Setup Miniconda
+ uses: conda-incubator/setup-miniconda@v2.2.0
+ with:
+ activate-environment: "build"
+ python-version: ${{ matrix.pyver }}
+ mamba-version: "*"
+ use-mamba: false
+ channels: conda-forge,defaults
+ channel-priority: true
+ add-pip-as-python-dependency: true
+ auto-activate-base: false
+
+ - name: Install Dependencies
+ run: |
+ conda install cuda-toolkit -c "nvidia/label/cuda-${env:CUDA_VERSION}.0"
+
+ # Refer to https://pytorch.org/get-started/locally/
+ python -m pip install torch --index-url https://download.pytorch.org/whl/cu121
+
+ python -m pip install --upgrade build setuptools wheel ninja numpy gekko pandas
+
+ - name: Check install
+ run: |
+ python -c "import torch; print('torch version:', torch.__version__)"
+
+ - name: Build Wheel
+ run: |
+ $env:CUDA_PATH = $env:CONDA_PREFIX
+ $env:CUDA_HOME = $env:CONDA_PREFIX
+
+ $env:TORCH_CUDA_ARCH_LIST = '6.0 6.1 7.0 7.5 8.0 8.6 8.9 9.0+PTX'
+
+ $env:PYPI_RELEASE = "1"
+
+ echo "CUDA_PATH:"
+ echo $env:CUDA_PATH
+
+ echo "PYPI_RELEASE:"
+ echo $env:PYPI_RELEASE
+
+ python setup.py sdist bdist_wheel
+
+ - uses: actions/upload-artifact@v3
+ with:
+ name: 'windows-cuda-wheels-pypi'
+ path: ./dist/*.whl
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/build_wheels_rocm.yml b/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/build_wheels_rocm.yml
new file mode 100644
index 0000000000000000000000000000000000000000..482fafb623755c9ddab1c7b62cb3e9bac1263311
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/build_wheels_rocm.yml
@@ -0,0 +1,131 @@
+name: Build AutoGPTQ Wheels with ROCm
+
+on: workflow_dispatch
+
+jobs:
+ build_wheels:
+ if: ${{ github.repository_owner == 'AutoGPTQ' }}
+
+ strategy:
+ matrix:
+ os: [ubuntu-20.04]
+ python: ["3.8", "3.9", "3.10", "3.11"]
+ rocm: ["5.7.3"] # we build only for ROCm 5.7 to match PyTorch 2.2.0 and PyTorch 2.2 nightly
+
+ name: Build wheels for ${{ matrix.os }} and Python ${{ matrix.python }} and RoCm ${{ matrix.rocm }}
+ runs-on: ${{ matrix.os }}
+
+ defaults:
+ run:
+ shell: bash
+
+ steps:
+ - uses: actions/checkout@v3
+
+ - name: Free disk space
+ run: |
+ # Go from 19G to 54G free disk space in 3min
+ df -h
+ sudo apt-get update
+ sudo apt-get purge -y '^apache.*'
+ sudo apt-get purge -y '^imagemagick.*'
+ sudo apt-get purge -y '^dotnet.*'
+ sudo apt-get purge -y '^aspnetcore.*'
+ sudo apt-get purge -y 'php.*'
+ sudo apt-get purge -y '^temurin.*'
+ sudo apt-get purge -y '^mysql.*'
+ sudo apt-get purge -y '^java.*'
+ sudo apt-get purge -y '^openjdk.*'
+ sudo apt-get purge -y microsoft-edge-stable google-cloud-cli azure-cli google-chrome-stable firefox powershell mono-devel
+ df -h
+ sudo apt-get autoremove -y >/dev/null 2>&1
+ sudo apt-get clean
+ df -h
+ echo "https://github.com/actions/virtual-environments/issues/709"
+ sudo rm -rf "$AGENT_TOOLSDIRECTORY"
+ df -h
+ echo "remove big /usr/local"
+ sudo rm -rf "/usr/local/share/boost"
+ sudo rm -rf /usr/local/lib/android >/dev/null 2>&1
+ df -h
+ echo "remove /usr/share leftovers"
+ sudo rm -rf /usr/share/dotnet/sdk > /dev/null 2>&1
+ sudo rm -rf /usr/share/dotnet/shared > /dev/null 2>&1
+ sudo rm -rf /usr/share/swift > /dev/null 2>&1
+ df -h
+ echo "remove other leftovers"
+ sudo rm -rf /var/lib/mysql > /dev/null 2>&1
+ sudo rm -rf /home/runner/.dotnet > /dev/null 2>&1
+ sudo rm -rf /home/runneradmin/.dotnet > /dev/null 2>&1
+ sudo rm -rf /etc/skel/.dotnet > /dev/null 2>&1
+ sudo rm -rf /usr/local/.ghcup > /dev/null 2>&1
+ sudo rm -rf /usr/local/aws-cli > /dev/null 2>&1
+ sudo rm -rf /usr/local/lib/node_modules > /dev/null 2>&1
+ sudo rm -rf /usr/lib/heroku > /dev/null 2>&1
+ sudo rm -rf /usr/local/share/chromium > /dev/null 2>&1
+ df -h
+
+ - uses: actions/setup-python@v3
+ with:
+ python-version: ${{ matrix.python }}
+
+ - name: Setup Miniconda
+ uses: conda-incubator/setup-miniconda@v2.2.0
+ with:
+ activate-environment: "build"
+ python-version: ${{ matrix.python }}
+ mamba-version: "*"
+ use-mamba: false
+ channels: conda-forge,defaults
+ channel-priority: true
+ add-pip-as-python-dependency: true
+ auto-activate-base: false
+
+ - name: Set up environment
+ run: |
+ echo "Using python:"
+ python --version
+ which python
+
+ if [[ "${{ matrix.rocm }}" == "5.4.2" ]]; then
+ export ROCM_DL_FILE=amdgpu-install_5.4.50402-1_all.deb
+ elif [[ "${{ matrix.rocm }}" == "5.6.1" ]]; then
+ export ROCM_DL_FILE=amdgpu-install_5.6.50601-1_all.deb
+ elif [[ "${{ matrix.rocm }}" == "5.7.3" ]]; then
+ export ROCM_DL_FILE=amdgpu-install_5.7.50703-1_all.deb
+ else
+ echo Unknown rocm version
+ exit 1
+ fi
+
+ curl -O https://repo.radeon.com/amdgpu-install/${{ matrix.rocm }}/ubuntu/focal/$ROCM_DL_FILE
+ sudo dpkg -i $ROCM_DL_FILE
+ sudo DEBIAN_FRONTEND=noninteractive amdgpu-install --usecase=rocm --no-dkms --no-32 -y
+
+ - name: Install dependencies
+ run: |
+ sudo apt-get update
+ sudo apt-get install -y --no-install-recommends rocsparse-dev rocthrust-dev rocblas-dev hipblas-dev hipsparse-dev
+
+ python -m pip install --upgrade build setuptools wheel ninja numpy gekko pandas
+
+ if [[ "${{ matrix.rocm }}" == "5.7.3" ]]; then
+ echo "Using PyTorch stable"
+ python -m pip install torch --index-url https://download.pytorch.org/whl/rocm5.7
+ else
+ echo Unknown rocm version for python install
+ exit 1
+ fi
+
+ - name: Build wheels
+ run: |
+ echo "Using python for build:"
+ python --version
+ which python
+
+ ROCM_VERSION=${{ matrix.rocm }} python setup.py sdist bdist_wheel
+
+ - uses: actions/upload-artifact@v3
+ with:
+ name: 'linux-rocm-wheels'
+ path: ./dist/*.whl
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/test_quality.yml b/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/test_quality.yml
new file mode 100644
index 0000000000000000000000000000000000000000..4e7d59802ee6f12262bd09e2916188c12c824093
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/.github/workflows/test_quality.yml
@@ -0,0 +1,124 @@
+name: check_code_quality
+
+on:
+ push:
+ branches: [ main ]
+ paths:
+ - "auto_gptq/**.py"
+ - "tests/**.py"
+ - "examples/**.py"
+ - "setup.py"
+
+ pull_request:
+ branches: [ main ]
+ paths:
+ - "auto_gptq/**.py"
+ - "tests/**.py"
+ - "examples/**.py"
+ - "setup.py"
+
+concurrency:
+ group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }}
+ cancel-in-progress: true
+
+jobs:
+ build:
+ strategy:
+ fail-fast: false
+ matrix:
+ python-version: [3.9]
+ os: [ubuntu-22.04]
+ runs-on: ${{ matrix.os }}
+
+ steps:
+ - uses: actions/checkout@v3
+
+ - name: Free disk space
+ run: |
+ # Go from 19G to 54G free disk space in 3min
+ df -h
+ sudo apt-get update
+ sudo apt-get purge -y '^apache.*'
+ sudo apt-get purge -y '^imagemagick.*'
+ sudo apt-get purge -y '^dotnet.*'
+ sudo apt-get purge -y '^aspnetcore.*'
+ sudo apt-get purge -y 'php.*'
+ sudo apt-get purge -y '^temurin.*'
+ sudo apt-get purge -y '^mysql.*'
+ sudo apt-get purge -y '^java.*'
+ sudo apt-get purge -y '^openjdk.*'
+ sudo apt-get purge -y microsoft-edge-stable google-cloud-cli azure-cli google-chrome-stable firefox powershell mono-devel
+ df -h
+ sudo apt-get autoremove -y >/dev/null 2>&1
+ sudo apt-get clean
+ df -h
+ echo "https://github.com/actions/virtual-environments/issues/709"
+ sudo rm -rf "$AGENT_TOOLSDIRECTORY"
+ df -h
+ echo "remove big /usr/local"
+ sudo rm -rf "/usr/local/share/boost"
+ sudo rm -rf /usr/local/lib/android >/dev/null 2>&1
+ df -h
+ echo "remove /usr/share leftovers"
+ sudo rm -rf /usr/share/dotnet/sdk > /dev/null 2>&1
+ sudo rm -rf /usr/share/dotnet/shared > /dev/null 2>&1
+ sudo rm -rf /usr/share/swift > /dev/null 2>&1
+ df -h
+ echo "remove other leftovers"
+ sudo rm -rf /var/lib/mysql > /dev/null 2>&1
+ sudo rm -rf /home/runner/.dotnet > /dev/null 2>&1
+ sudo rm -rf /home/runneradmin/.dotnet > /dev/null 2>&1
+ sudo rm -rf /etc/skel/.dotnet > /dev/null 2>&1
+ sudo rm -rf /usr/local/.ghcup > /dev/null 2>&1
+ sudo rm -rf /usr/local/aws-cli > /dev/null 2>&1
+ sudo rm -rf /usr/local/lib/node_modules > /dev/null 2>&1
+ sudo rm -rf /usr/lib/heroku > /dev/null 2>&1
+ sudo rm -rf /usr/local/share/chromium > /dev/null 2>&1
+ df -h
+
+ - uses: actions/setup-python@v3
+ with:
+ python-version: ${{ matrix.python-version }}
+
+ - name: Setup Miniconda
+ uses: conda-incubator/setup-miniconda@v2.2.0
+ with:
+ activate-environment: "build"
+ python-version: ${{ matrix.python-version }}
+ mamba-version: "*"
+ use-mamba: false
+ channels: conda-forge,defaults
+ channel-priority: true
+ add-pip-as-python-dependency: true
+ auto-activate-base: false
+
+ - name: Install dependencies
+ run: |
+ conda install cuda-toolkit -c "nvidia/label/cuda-12.1.0"
+
+ # Refer to https://pytorch.org/get-started/locally/
+ python -m pip install torch
+
+ python -m pip install --upgrade build setuptools wheel numpy
+
+ - name: Check install
+ run: |
+ python -c "import torch; print('torch version:', torch.__version__)"
+
+ - name: Install AutoGPTQ
+ run: |
+ # For some reason $CONDA_PREFIX is empty.
+ export CUDA_HOME=/usr/share/miniconda
+ export CUDA_PATH=/usr/share/miniconda
+
+ echo "CUDA_HOME:"
+ echo $CUDA_HOME
+
+ echo "CUDA_PATH:"
+ echo $CUDA_PATH
+
+ pip install -vvv .[quality]
+
+ - name: Check style with ruff
+ run: |
+ ruff auto_gptq examples tests setup.py
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/Dockerfile b/lm-quant-toolkit/.deps/AutoGPTQ/Dockerfile
new file mode 100644
index 0000000000000000000000000000000000000000..25008519b8b9d8b946037ee8ed3a4d23df78a1df
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/Dockerfile
@@ -0,0 +1,28 @@
+# Build with: `docker build -f Dockerfile -t autogptq .`
+# Run with: `docker run --gpus all --rm -it autogptq:latest /bin/bash`
+
+FROM nvcr.io/nvidia/cuda:12.1.0-runtime-ubuntu22.04
+
+RUN apt update && \
+ apt install -y wget git && \
+ apt clean && \
+ rm -rf /var/lib/apt/lists/* /tmp/* /var/tmp/*
+
+ENV PATH="/root/miniconda3/bin:${PATH}"
+ARG PATH="/root/miniconda3/bin:${PATH}"
+
+RUN wget \
+ https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh \
+ && mkdir .conda \
+ && bash Miniconda3-latest-Linux-x86_64.sh -b \
+ && rm -f Miniconda3-latest-Linux-x86_64.sh
+
+RUN conda init bash
+
+RUN pip install --upgrade pip
+RUN pip install --upgrade numpy torch setuptools wheel
+
+RUN git clone https://github.com/AutoGPTQ/AutoGPTQ.git
+WORKDIR /AutoGPTQ
+
+RUN pip install -vvv .
\ No newline at end of file
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/Dockerfile_amd b/lm-quant-toolkit/.deps/AutoGPTQ/Dockerfile_amd
new file mode 100644
index 0000000000000000000000000000000000000000..116b6fa7a4bda65bba9fea17b65fd38a0ff4ac5b
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/Dockerfile_amd
@@ -0,0 +1,35 @@
+# Build with: `docker build -f Dockerfile_amd -t autogptq-rocm .`
+# Run with: `docker run --rm -it --shm-size=150G --device /dev/kfd --device /dev/dri --net host --group-add=video --ipc=host --cap-add=SYS_PTRACE --security-opt seccomp=unconfined autogptq-rocm:latest /bin/bash`
+
+FROM rocm/dev-ubuntu-22.04:5.7
+
+RUN apt update && \
+ apt install -y wget \
+ git \
+ rocsparse-dev \
+ hipsparse-dev \
+ rocthrust-dev \
+ rocblas-dev \
+ hipblas-dev && \
+ apt clean && \
+ rm -rf /var/lib/apt/lists/* /tmp/* /var/tmp/*
+
+ENV PATH="/root/miniconda3/bin:${PATH}"
+ARG PATH="/root/miniconda3/bin:${PATH}"
+
+RUN wget \
+ https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh \
+ && mkdir .conda \
+ && bash Miniconda3-latest-Linux-x86_64.sh -b \
+ && rm -f Miniconda3-latest-Linux-x86_64.sh
+
+RUN conda init bash
+
+RUN pip install --upgrade pip
+RUN pip install --upgrade numpy setuptools wheel ninja packaging
+RUN pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/rocm5.7
+
+RUN git clone https://github.com/AutoGPTQ/AutoGPTQ.git
+WORKDIR /AutoGPTQ
+
+RUN ROCM_VERSION="5.7" pip install -vvv .
\ No newline at end of file
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/LICENSE b/lm-quant-toolkit/.deps/AutoGPTQ/LICENSE
new file mode 100644
index 0000000000000000000000000000000000000000..a3beacee8f8a2cf3380fb359f8367e3eb3f644c8
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/LICENSE
@@ -0,0 +1,21 @@
+MIT License
+
+Copyright (c) 2023 潘其威(William)
+
+Permission is hereby granted, free of charge, to any person obtaining a copy
+of this software and associated documentation files (the "Software"), to deal
+in the Software without restriction, including without limitation the rights
+to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+copies of the Software, and to permit persons to whom the Software is
+furnished to do so, subject to the following conditions:
+
+The above copyright notice and this permission notice shall be included in all
+copies or substantial portions of the Software.
+
+THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+SOFTWARE.
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/MANIFEST.in b/lm-quant-toolkit/.deps/AutoGPTQ/MANIFEST.in
new file mode 100644
index 0000000000000000000000000000000000000000..3e2c6d1fa2ebb66a6219da059e3f6125a568bc8f
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/MANIFEST.in
@@ -0,0 +1,5 @@
+global-include autogptq_extension/**/*.cuh
+global-include autogptq_extension/**/*.h
+global-include autogptq_extension/**/*.cpp
+global-include autogptq_extension/**/*.cu
+global-include autogptq_extension/**/*.py
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/Makefile b/lm-quant-toolkit/.deps/AutoGPTQ/Makefile
new file mode 100644
index 0000000000000000000000000000000000000000..679730a7f4e41cda1602f87daf5779811950c487
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/Makefile
@@ -0,0 +1,2 @@
+style:
+ ruff auto_gptq examples tests setup.py --fix
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/README.md b/lm-quant-toolkit/.deps/AutoGPTQ/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..d184848ac2092f43cf7934567391e90b47181683
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/README.md
@@ -0,0 +1,331 @@
+AutoGPTQ
+An easy-to-use LLM quantization package with user-friendly APIs, based on GPTQ algorithm (weight-only quantization).
+
+
+  +
+
+
 +
+
+
+
+ English |
+ 中文
+
+
+
+## News or Update
+
+- 2024-02-15 - (News) - AutoGPTQ 0.7.0 is released, with [Marlin](https://github.com/IST-DASLab/marlin) int4*fp16 matrix multiplication kernel support, with the argument `use_marlin=True` when loading models.
+- 2023-08-23 - (News) - 🤗 Transformers, optimum and peft have integrated `auto-gptq`, so now running and training GPTQ models can be more available to everyone! See [this blog](https://huggingface.co/blog/gptq-integration) and it's resources for more details!
+
+*For more histories please turn to [here](docs/NEWS_OR_UPDATE.md)*
+
+## Performance Comparison
+
+### Inference Speed
+> The result is generated using [this script](examples/benchmark/generation_speed.py), batch size of input is 1, decode strategy is beam search and enforce the model to generate 512 tokens, speed metric is tokens/s (the larger, the better).
+>
+> The quantized model is loaded using the setup that can gain the fastest inference speed.
+
+| model | GPU | num_beams | fp16 | gptq-int4 |
+|---------------|---------------|-----------|-------|-----------|
+| llama-7b | 1xA100-40G | 1 | 18.87 | 25.53 |
+| llama-7b | 1xA100-40G | 4 | 68.79 | 91.30 |
+| moss-moon 16b | 1xA100-40G | 1 | 12.48 | 15.25 |
+| moss-moon 16b | 1xA100-40G | 4 | OOM | 42.67 |
+| moss-moon 16b | 2xA100-40G | 1 | 06.83 | 06.78 |
+| moss-moon 16b | 2xA100-40G | 4 | 13.10 | 10.80 |
+| gpt-j 6b | 1xRTX3060-12G | 1 | OOM | 29.55 |
+| gpt-j 6b | 1xRTX3060-12G | 4 | OOM | 47.36 |
+
+
+### Perplexity
+For perplexity comparison, you can turn to [here](https://github.com/qwopqwop200/GPTQ-for-LLaMa#result) and [here](https://github.com/qwopqwop200/GPTQ-for-LLaMa#gptq-vs-bitsandbytes)
+
+## Installation
+
+AutoGPTQ is available on Linux and Windows only. You can install the latest stable release of AutoGPTQ from pip with pre-built wheels:
+
+| CUDA/ROCm version | Installation | Built against PyTorch |
+|-------------------|---------------------------------------------------------------------------------------------------|-----------------------|
+| CUDA 11.8 | `pip install auto-gptq --no-build-isolation --extra-index-url https://huggingface.github.io/autogptq-index/whl/cu118/` | 2.2.1+cu118 |
+| CUDA 12.1 | `pip install auto-gptq --no-build-isolation` | 2.2.1+cu121 |
+| ROCm 5.7 | `pip install auto-gptq --no-build-isolation --extra-index-url https://huggingface.github.io/autogptq-index/whl/rocm573/` | 2.2.1+rocm5.7 |
+
+AutoGPTQ can be installed with the Triton dependency with `pip install auto-gptq[triton] --no-build-isolation` in order to be able to use the Triton backend (currently only supports linux, no 3-bits quantization).
+
+For older AutoGPTQ, please refer to [the previous releases installation table](docs/INSTALLATION.md).
+
+On NVIDIA systems, AutoGPTQ does not support [Maxwell or lower](https://qiita.com/uyuni/items/733a93b975b524f89f46) GPUs.
+
+### Install from source
+
+Clone the source code:
+```bash
+git clone https://github.com/PanQiWei/AutoGPTQ.git && cd AutoGPTQ
+```
+
+A few packages are required in order to build from source: `pip install numpy gekko pandas`.
+
+Then, install locally from source:
+```bash
+pip install -vvv --no-build-isolation -e .
+```
+You can set `BUILD_CUDA_EXT=0` to disable pytorch extension building, but this is **strongly discouraged** as AutoGPTQ then falls back on a slow python implementation.
+
+As a last resort, if the above command fails, you can try `python setup.py install`.
+
+#### On ROCm systems
+
+To install from source for AMD GPUs supporting ROCm, please specify the `ROCM_VERSION` environment variable. Example:
+
+```bash
+ROCM_VERSION=5.6 pip install -vvv --no-build-isolation -e .
+```
+
+The compilation can be speeded up by specifying the `PYTORCH_ROCM_ARCH` variable ([reference](https://github.com/pytorch/pytorch/blob/7b73b1e8a73a1777ebe8d2cd4487eb13da55b3ba/setup.py#L132)) in order to build for a single target device, for example `gfx90a` for MI200 series devices.
+
+For ROCm systems, the packages `rocsparse-dev`, `hipsparse-dev`, `rocthrust-dev`, `rocblas-dev` and `hipblas-dev` are required to build.
+
+## Quick Tour
+
+### Quantization and Inference
+> warning: this is just a showcase of the usage of basic apis in AutoGPTQ, which uses only one sample to quantize a much small model, quality of quantized model using such little samples may not good.
+
+Below is an example for the simplest use of `auto_gptq` to quantize a model and inference after quantization:
+```python
+from transformers import AutoTokenizer, TextGenerationPipeline
+from auto_gptq import AutoGPTQForCausalLM, BaseQuantizeConfig
+import logging
+
+logging.basicConfig(
+ format="%(asctime)s %(levelname)s [%(name)s] %(message)s", level=logging.INFO, datefmt="%Y-%m-%d %H:%M:%S"
+)
+
+pretrained_model_dir = "facebook/opt-125m"
+quantized_model_dir = "opt-125m-4bit"
+
+tokenizer = AutoTokenizer.from_pretrained(pretrained_model_dir, use_fast=True)
+examples = [
+ tokenizer(
+ "auto-gptq is an easy-to-use model quantization library with user-friendly apis, based on GPTQ algorithm."
+ )
+]
+
+quantize_config = BaseQuantizeConfig(
+ bits=4, # quantize model to 4-bit
+ group_size=128, # it is recommended to set the value to 128
+ desc_act=False, # set to False can significantly speed up inference but the perplexity may slightly bad
+)
+
+# load un-quantized model, by default, the model will always be loaded into CPU memory
+model = AutoGPTQForCausalLM.from_pretrained(pretrained_model_dir, quantize_config)
+
+# quantize model, the examples should be list of dict whose keys can only be "input_ids" and "attention_mask"
+model.quantize(examples)
+
+# save quantized model
+model.save_quantized(quantized_model_dir)
+
+# save quantized model using safetensors
+model.save_quantized(quantized_model_dir, use_safetensors=True)
+
+# push quantized model to Hugging Face Hub.
+# to use use_auth_token=True, Login first via huggingface-cli login.
+# or pass explcit token with: use_auth_token="hf_xxxxxxx"
+# (uncomment the following three lines to enable this feature)
+# repo_id = f"YourUserName/{quantized_model_dir}"
+# commit_message = f"AutoGPTQ model for {pretrained_model_dir}: {quantize_config.bits}bits, gr{quantize_config.group_size}, desc_act={quantize_config.desc_act}"
+# model.push_to_hub(repo_id, commit_message=commit_message, use_auth_token=True)
+
+# alternatively you can save and push at the same time
+# (uncomment the following three lines to enable this feature)
+# repo_id = f"YourUserName/{quantized_model_dir}"
+# commit_message = f"AutoGPTQ model for {pretrained_model_dir}: {quantize_config.bits}bits, gr{quantize_config.group_size}, desc_act={quantize_config.desc_act}"
+# model.push_to_hub(repo_id, save_dir=quantized_model_dir, use_safetensors=True, commit_message=commit_message, use_auth_token=True)
+
+# load quantized model to the first GPU
+model = AutoGPTQForCausalLM.from_quantized(quantized_model_dir, device="cuda:0")
+
+# download quantized model from Hugging Face Hub and load to the first GPU
+# model = AutoGPTQForCausalLM.from_quantized(repo_id, device="cuda:0", use_safetensors=True, use_triton=False)
+
+# inference with model.generate
+print(tokenizer.decode(model.generate(**tokenizer("auto_gptq is", return_tensors="pt").to(model.device))[0]))
+
+# or you can also use pipeline
+pipeline = TextGenerationPipeline(model=model, tokenizer=tokenizer)
+print(pipeline("auto-gptq is")[0]["generated_text"])
+```
+
+For more advanced features of model quantization, please reference to [this script](examples/quantization/quant_with_alpaca.py)
+
+### Customize Model
+
+
+Below is an example to extend `auto_gptq` to support `OPT` model, as you will see, it's very easy:
+
+```python
+from auto_gptq.modeling import BaseGPTQForCausalLM
+
+
+class OPTGPTQForCausalLM(BaseGPTQForCausalLM):
+ # chained attribute name of transformer layer block
+ layers_block_name = "model.decoder.layers"
+ # chained attribute names of other nn modules that in the same level as the transformer layer block
+ outside_layer_modules = [
+ "model.decoder.embed_tokens", "model.decoder.embed_positions", "model.decoder.project_out",
+ "model.decoder.project_in", "model.decoder.final_layer_norm"
+ ]
+ # chained attribute names of linear layers in transformer layer module
+ # normally, there are four sub lists, for each one the modules in it can be seen as one operation,
+ # and the order should be the order when they are truly executed, in this case (and usually in most cases),
+ # they are: attention q_k_v projection, attention output projection, MLP project input, MLP project output
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.out_proj"],
+ ["fc1"],
+ ["fc2"]
+ ]
+```
+After this, you can use `OPTGPTQForCausalLM.from_pretrained` and other methods as shown in Basic.
+
+
+
+### Evaluation on Downstream Tasks
+You can use tasks defined in `auto_gptq.eval_tasks` to evaluate model's performance on specific down-stream task before and after quantization.
+
+The predefined tasks support all causal-language-models implemented in [🤗 transformers](https://github.com/huggingface/transformers) and in this project.
+
+
+
+Below is an example to evaluate `EleutherAI/gpt-j-6b` on sequence-classification task using `cardiffnlp/tweet_sentiment_multilingual` dataset:
+
+```python
+from functools import partial
+
+import datasets
+from transformers import AutoTokenizer, AutoModelForCausalLM, GenerationConfig
+
+from auto_gptq import AutoGPTQForCausalLM, BaseQuantizeConfig
+from auto_gptq.eval_tasks import SequenceClassificationTask
+
+
+MODEL = "EleutherAI/gpt-j-6b"
+DATASET = "cardiffnlp/tweet_sentiment_multilingual"
+TEMPLATE = "Question:What's the sentiment of the given text? Choices are {labels}.\nText: {text}\nAnswer:"
+ID2LABEL = {
+ 0: "negative",
+ 1: "neutral",
+ 2: "positive"
+}
+LABELS = list(ID2LABEL.values())
+
+
+def ds_refactor_fn(samples):
+ text_data = samples["text"]
+ label_data = samples["label"]
+
+ new_samples = {"prompt": [], "label": []}
+ for text, label in zip(text_data, label_data):
+ prompt = TEMPLATE.format(labels=LABELS, text=text)
+ new_samples["prompt"].append(prompt)
+ new_samples["label"].append(ID2LABEL[label])
+
+ return new_samples
+
+
+# model = AutoModelForCausalLM.from_pretrained(MODEL).eval().half().to("cuda:0")
+model = AutoGPTQForCausalLM.from_pretrained(MODEL, BaseQuantizeConfig())
+tokenizer = AutoTokenizer.from_pretrained(MODEL)
+
+task = SequenceClassificationTask(
+ model=model,
+ tokenizer=tokenizer,
+ classes=LABELS,
+ data_name_or_path=DATASET,
+ prompt_col_name="prompt",
+ label_col_name="label",
+ **{
+ "num_samples": 1000, # how many samples will be sampled to evaluation
+ "sample_max_len": 1024, # max tokens for each sample
+ "block_max_len": 2048, # max tokens for each data block
+ # function to load dataset, one must only accept data_name_or_path as input
+ # and return datasets.Dataset
+ "load_fn": partial(datasets.load_dataset, name="english"),
+ # function to preprocess dataset, which is used for datasets.Dataset.map,
+ # must return Dict[str, list] with only two keys: [prompt_col_name, label_col_name]
+ "preprocess_fn": ds_refactor_fn,
+ # truncate label when sample's length exceed sample_max_len
+ "truncate_prompt": False
+ }
+ )
+
+# note that max_new_tokens will be automatically specified internally based on given classes
+print(task.run())
+
+# self-consistency
+print(
+ task.run(
+ generation_config=GenerationConfig(
+ num_beams=3,
+ num_return_sequences=3,
+ do_sample=True
+ )
+ )
+)
+```
+
+
+
+## Learn More
+[tutorials](docs/tutorial) provide step-by-step guidance to integrate `auto_gptq` with your own project and some best practice principles.
+
+[examples](examples/README.md) provide plenty of example scripts to use `auto_gptq` in different ways.
+
+## Supported Models
+
+> you can use `model.config.model_type` to compare with the table below to check whether the model you use is supported by `auto_gptq`.
+>
+> for example, model_type of `WizardLM`, `vicuna` and `gpt4all` are all `llama`, hence they are all supported by `auto_gptq`.
+
+| model type | quantization | inference | peft-lora | peft-ada-lora | peft-adaption_prompt |
+|------------------------------------|--------------|-----------|-----------|---------------|-------------------------------------------------------------------------------------------------|
+| bloom | ✅ | ✅ | ✅ | ✅ | |
+| gpt2 | ✅ | ✅ | ✅ | ✅ | |
+| gpt_neox | ✅ | ✅ | ✅ | ✅ | ✅[requires this peft branch](https://github.com/PanQiWei/peft/tree/multi_modal_adaption_prompt) |
+| gptj | ✅ | ✅ | ✅ | ✅ | ✅[requires this peft branch](https://github.com/PanQiWei/peft/tree/multi_modal_adaption_prompt) |
+| llama | ✅ | ✅ | ✅ | ✅ | ✅ |
+| moss | ✅ | ✅ | ✅ | ✅ | ✅[requires this peft branch](https://github.com/PanQiWei/peft/tree/multi_modal_adaption_prompt) |
+| opt | ✅ | ✅ | ✅ | ✅ | |
+| gpt_bigcode | ✅ | ✅ | ✅ | ✅ | |
+| codegen | ✅ | ✅ | ✅ | ✅ | |
+| falcon(RefinedWebModel/RefinedWeb) | ✅ | ✅ | ✅ | ✅ | |
+
+## Supported Evaluation Tasks
+Currently, `auto_gptq` supports: `LanguageModelingTask`, `SequenceClassificationTask` and `TextSummarizationTask`; more Tasks will come soon!
+
+## Running tests
+
+Tests can be run with:
+
+```
+pytest tests/ -s
+```
+
+## FAQ
+
+### Which kernel is used by default?
+
+AutoGPTQ defaults to using exllamav2 int4*fp16 kernel for matrix multiplication.
+
+### How to use Marlin kernel?
+
+Marlin is an optimized int4 * fp16 kernel was recently proposed at https://github.com/IST-DASLab/marlin. This is integrated in AutoGPTQ when loading a model with `use_marlin=True`. This kernel is available only on devices with compute capability 8.0 or 8.6 (Ampere GPUs).
+
+## Acknowledgement
+- Special thanks **Elias Frantar**, **Saleh Ashkboos**, **Torsten Hoefler** and **Dan Alistarh** for proposing **GPTQ** algorithm and open source the [code](https://github.com/IST-DASLab/gptq), and for releasing [Marlin kernel](https://github.com/IST-DASLab/marlin) for mixed precision computation.
+- Special thanks **qwopqwop200**, for code in this project that relevant to quantization are mainly referenced from [GPTQ-for-LLaMa](https://github.com/qwopqwop200/GPTQ-for-LLaMa/tree/cuda).
+- Special thanks to **turboderp**, for releasing [Exllama](https://github.com/turboderp/exllama) and [Exllama v2](https://github.com/turboderp/exllamav2) libraries with efficient mixed precision kernels.
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/README_zh.md b/lm-quant-toolkit/.deps/AutoGPTQ/README_zh.md
new file mode 100644
index 0000000000000000000000000000000000000000..31032d1fdb9ace6349a3f35c044b3477ee4d82ed
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/README_zh.md
@@ -0,0 +1,336 @@
+AutoGPTQ
+一个基于 GPTQ 算法,简单易用且拥有用户友好型接口的大语言模型量化工具包。
+
+
+
+
+
+
+
+
+
+
+ English |
+ 中文
+
+
+
+Note: The English README is likely to be more up to date.
+
+## 通向 v1.0.0 之路
+
+嗨,社区的伙伴们,好久不见!很抱歉这段时间由于个人原因,我没能以较高的频率来更新这个项目。过去几周对我的职业生涯规划而言意义重大。在不久前,我正式告别了毕业后便加入两年之久的创业团队,非常感谢团队的领导和同事们给予我的信任与指导,让我能够在两年时间里飞速地成长;同时也十分感激团队允许我自 AutoGPTQ 项目创立以来一直无偿使用内部的 A100 GPU 服务器集群以完成各项实验与性能测评。(当然今后是无法继续使用了,因此**若有新的硬件赞助我将感激不尽**!)过去的两年里,我在这个团队中担任算法工程师的角色,负责基于大语言模型的对话系统架构设计与开发,我们曾成功推出一款名为 gemsouls 的产品,但不幸的是它已经停止运营。而现在,这个团队即将推出一款名为 [modelize](https://www.beta.modelize.ai/) 的新产品,**这是一个大模型原生的 AI 智能体平台,用户可以使用多个 AI 智能体搭建一个高度自动化的团队,让它们在工作流中相互合作,高效完成复杂的项目。**
+
+话归正题,我非常兴奋地看到,在过去几个月的时间里,针对大语言模型推理性能优化的研究取得了巨大的进展,如今我们不仅能够在高端显卡上完成大语言模型的推理,甚至在 CPU 和边缘设备上都可以轻松运行大语言模型。一系列的技术进步,让我同样迫不及待地在开源社区上做出更多的贡献,因此,首先,我将用约四周的时间将 AutoGPTQ 迭代至 v1.0.0 正式版本,在此期间,也会有 2~3 个小版本发布以让用户能够及时体验性能优化和新特性。在我的愿景里,**到 v1.0.0 版本正式发布时,AutoGPTQ 将能够作为一个灵活可拓展的、支持所有 GPTQ-like 方法的量化后端,自动地完成各种基于 Pytorch 编写的大语言模型的量化工作**。我在[这里](https://github.com/PanQiWei/AutoGPTQ/issues/348)详细介绍了开发计划,欢迎移步至此进行讨论并给出你们的建议!
+
+## 新闻或更新
+
+- 2023-08-23 - (新闻) - 🤗 Transformers、optimum 和 peft 完成了对 `auto-gptq` 的集成,现在使用 GPTQ 模型进行推理和训练将变得更容易!阅读 [这篇博客](https://huggingface.co/blog/gptq-integration) 和相关资源以了解更多细节!
+- 2023-08-21 - (新闻) - 通义千问团队发布了基于 `auto-gptq` 的 Qwen-7B 4bit 量化版本模型,并提供了[详尽的测评结果](https://huggingface.co/Qwen/Qwen-7B-Chat-Int4#%E9%87%8F%E5%8C%96-quantization)
+- 2023-08-06 - (更新) - 支持 exllama 的 q4 CUDA 算子使得 int4 量化模型能够获得至少1.3倍的推理速度提升.
+- 2023-08-04 - (更新) - 支持 RoCm 使得 AMD GPU 的用户能够使用 auto-gptq 的 CUDA 拓展.
+- 2023-07-26 - (更新) - 一个优雅的 [PPL 测评脚本](examples/benchmark/perplexity.py)以获得可以与诸如 `llama.cpp` 等代码库进行公平比较的结果。
+- 2023-06-05 - (更新) - 集成 🤗 peft 来使用 gptq 量化过的模型训练适应层,支持 LoRA,AdaLoRA,AdaptionPrompt 等。
+- 2023-05-30 - (更新) - 支持从 🤗 Hub 下载量化好的模型或上次量化好的模型到 🤗 Hub。
+
+*获取更多的历史信息,请转至[这里](docs/NEWS_OR_UPDATE.md)*
+
+## 性能对比
+
+### 推理速度
+> 以下结果通过[这个脚本](examples/benchmark/generation_speed.py)生成,文本输入的 batch size 为1,解码策略为 beam search 并且强制模型生成512个 token,速度的计量单位为 tokens/s(越大越好)。
+>
+> 量化模型通过能够最大化推理速度的方式加载。
+
+| model | GPU | num_beams | fp16 | gptq-int4 |
+|---------------|---------------|-----------|-------|-----------|
+| llama-7b | 1xA100-40G | 1 | 18.87 | 25.53 |
+| llama-7b | 1xA100-40G | 4 | 68.79 | 91.30 |
+| moss-moon 16b | 1xA100-40G | 1 | 12.48 | 15.25 |
+| moss-moon 16b | 1xA100-40G | 4 | OOM | 42.67 |
+| moss-moon 16b | 2xA100-40G | 1 | 06.83 | 06.78 |
+| moss-moon 16b | 2xA100-40G | 4 | 13.10 | 10.80 |
+| gpt-j 6b | 1xRTX3060-12G | 1 | OOM | 29.55 |
+| gpt-j 6b | 1xRTX3060-12G | 4 | OOM | 47.36 |
+
+
+### 困惑度(PPL)
+对于困惑度的对比, 你可以参考 [这里](https://github.com/qwopqwop200/GPTQ-for-LLaMa#result) 和 [这里](https://github.com/qwopqwop200/GPTQ-for-LLaMa#gptq-vs-bitsandbytes)
+
+## 安装
+
+### 快速安装
+你可以通过 pip 来安装与 PyTorch 2.0.1 相兼容的最新稳定版本的 AutoGPTQ 的预构建轮子文件:
+
+* 对于 CUDA 11.7: `pip install auto-gptq --extra-index-url https://huggingface.github.io/autogptq-index/whl/cu117/`
+* 对于 CUDA 11.8: `pip install auto-gptq --extra-index-url https://huggingface.github.io/autogptq-index/whl/cu118/`
+* 对于 RoCm 5.4.2: `pip install auto-gptq --extra-index-url https://huggingface.github.io/autogptq-index/whl/rocm542/`
+
+**警告:** 预构建的轮子文件不一定在 PyTorch 的 nightly 版本上有效。如果要使用 PyTorch 的 nightly 版本,请从源码安装 AutoGPTQ。
+
+#### 取消 cuda 拓展的安装
+默认情况下,在 `torch` 和 `cuda` 已经于你的机器上被安装时,cuda 拓展将被自动安装,如果你不想要这些拓展的话,采用以下安装命令:
+```shell
+BUILD_CUDA_EXT=0 pip install auto-gptq
+```
+同时为确保该拓展——`autogptq_cuda` 不再存在于你的虚拟环境,执行以下命令:
+```shell
+pip uninstall autogptq_cuda -y
+```
+
+#### 支持使用 triton 加速
+若想使用 `triton` 加速模型推理,使用以下命令:
+> 警告:目前 triton 仅支持 linux 操作系统;当使用 triton 时 3-bit 数值类型的量化将不被支持
+
+```shell
+pip install auto-gptq[triton]
+```
+
+### 从源码安装
+
+点击以查看详情
+
+克隆源码:
+```shell
+git clone https://github.com/PanQiWei/AutoGPTQ.git && cd AutoGPTQ
+```
+然后,从项目目录安装:
+```shell
+pip install .
+```
+正如在快速安装一节,你可以使用 `BUILD_CUDA_EXT=0` 来取消构建 cuda 拓展。
+
+如果你想要使用 triton 加速且其能够被你的操作系统所支持,请使用 `.[triton]`。
+
+对应 AMD GPUs,为了从源码安装以支持 RoCm,请设置 `ROCM_VERSION` 环境变量。同时通过设置 `PYTORCH_ROCM_ARCH` ([reference](https://github.com/pytorch/pytorch/blob/7b73b1e8a73a1777ebe8d2cd4487eb13da55b3ba/setup.py#L132)) 可提升编译速度,例如:对于 MI200 系列设备,该变量可设为 `gfx90a`。例子:
+
+```
+ROCM_VERSION=5.6 pip install .
+```
+
+对于 RoCm 系统,在从源码安装时额外需要提前安装以下包:`rocsparse-dev`, `hipsparse-dev`, `rocthrust-dev`, `rocblas-dev` and `hipblas-dev`。
+
+
+
+## 快速开始
+
+### 量化和推理
+> 警告:这里仅是对 AutoGPTQ 中基本接口的用法展示,只使用了一条文本来量化一个特别小的模型,因此其结果的表现可能不如在大模型上执行量化后预期的那样好。
+
+以下展示了使用 `auto_gptq` 进行量化和推理的最简单用法:
+```python
+from transformers import AutoTokenizer, TextGenerationPipeline
+from auto_gptq import AutoGPTQForCausalLM, BaseQuantizeConfig
+
+
+pretrained_model_dir = "facebook/opt-125m"
+quantized_model_dir = "opt-125m-4bit"
+
+
+tokenizer = AutoTokenizer.from_pretrained(pretrained_model_dir, use_fast=True)
+examples = [
+ tokenizer(
+ "auto-gptq is an easy-to-use model quantization library with user-friendly apis, based on GPTQ algorithm."
+ )
+]
+
+quantize_config = BaseQuantizeConfig(
+ bits=4, # 将模型量化为 4-bit 数值类型
+ group_size=128, # 一般推荐将此参数的值设置为 128
+ desc_act=False, # 设为 False 可以显著提升推理速度,但是 ppl 可能会轻微地变差
+)
+
+# 加载未量化的模型,默认情况下,模型总是会被加载到 CPU 内存中
+model = AutoGPTQForCausalLM.from_pretrained(pretrained_model_dir, quantize_config)
+
+# 量化模型, 样本的数据类型应该为 List[Dict],其中字典的键有且仅有 input_ids 和 attention_mask
+model.quantize(examples)
+
+# 保存量化好的模型
+model.save_quantized(quantized_model_dir)
+
+# 使用 safetensors 保存量化好的模型
+model.save_quantized(quantized_model_dir, use_safetensors=True)
+
+# 将量化好的模型直接上传至 Hugging Face Hub
+# 当使用 use_auth_token=True 时, 确保你已经首先使用 huggingface-cli login 进行了登录
+# 或者可以使用 use_auth_token="hf_xxxxxxx" 来显式地添加账户认证 token
+# (取消下面三行代码的注释来使用该功能)
+# repo_id = f"YourUserName/{quantized_model_dir}"
+# commit_message = f"AutoGPTQ model for {pretrained_model_dir}: {quantize_config.bits}bits, gr{quantize_config.group_size}, desc_act={quantize_config.desc_act}"
+# model.push_to_hub(repo_id, commit_message=commit_message, use_auth_token=True)
+
+# 或者你也可以同时将量化好的模型保存到本地并上传至 Hugging Face Hub
+# (取消下面三行代码的注释来使用该功能)
+# repo_id = f"YourUserName/{quantized_model_dir}"
+# commit_message = f"AutoGPTQ model for {pretrained_model_dir}: {quantize_config.bits}bits, gr{quantize_config.group_size}, desc_act={quantize_config.desc_act}"
+# model.push_to_hub(repo_id, save_dir=quantized_model_dir, use_safetensors=True, commit_message=commit_message, use_auth_token=True)
+
+# 加载量化好的模型到能被识别到的第一块显卡中
+model = AutoGPTQForCausalLM.from_quantized(quantized_model_dir, device="cuda:0")
+
+# 从 Hugging Face Hub 下载量化好的模型并加载到能被识别到的第一块显卡中
+# model = AutoGPTQForCausalLM.from_quantized(repo_id, device="cuda:0", use_safetensors=True, use_triton=False)
+
+# 使用 model.generate 执行推理
+print(tokenizer.decode(model.generate(**tokenizer("auto_gptq is", return_tensors="pt").to(model.device))[0]))
+
+# 或者使用 TextGenerationPipeline
+pipeline = TextGenerationPipeline(model=model, tokenizer=tokenizer)
+print(pipeline("auto-gptq is")[0]["generated_text"])
+```
+
+参考 [此样例脚本](examples/quantization/quant_with_alpaca.py) 以了解进阶的用法。
+
+### 自定义模型
+
+
+
+以下展示了如何拓展 `auto_gptq` 以支持 `OPT` 模型,如你所见,这非常简单:
+
+```python
+from auto_gptq.modeling import BaseGPTQForCausalLM
+
+
+class OPTGPTQForCausalLM(BaseGPTQForCausalLM):
+ # chained attribute name of transformer layer block
+ layers_block_name = "model.decoder.layers"
+ # chained attribute names of other nn modules that in the same level as the transformer layer block
+ outside_layer_modules = [
+ "model.decoder.embed_tokens", "model.decoder.embed_positions", "model.decoder.project_out",
+ "model.decoder.project_in", "model.decoder.final_layer_norm"
+ ]
+ # chained attribute names of linear layers in transformer layer module
+ # normally, there are four sub lists, for each one the modules in it can be seen as one operation,
+ # and the order should be the order when they are truly executed, in this case (and usually in most cases),
+ # they are: attention q_k_v projection, attention output projection, MLP project input, MLP project output
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.out_proj"],
+ ["fc1"],
+ ["fc2"]
+ ]
+```
+然后, 你就可以像在基本用法一节中展示的那样使用 `OPTGPTQForCausalLM.from_pretrained` 和其他方法。
+
+
+
+
+### 在下游任务上执行评估
+你可以使用在 `auto_gptq.eval_tasks` 中定义的任务来评估量化前后的模型在某个特定下游任务上的表现。
+
+这些预定义的模型支持所有在 [🤗 transformers](https://github.com/huggingface/transformers)和本项目中被实现了的 causal-language-models。
+
+
+
+以下是使用 `cardiffnlp/tweet_sentiment_multilingual` 数据集在序列分类(文本分类)任务上评估 `EleutherAI/gpt-j-6b` 模型的示例:
+
+```python
+from functools import partial
+
+import datasets
+from transformers import AutoTokenizer, AutoModelForCausalLM, GenerationConfig
+
+from auto_gptq import AutoGPTQForCausalLM, BaseQuantizeConfig
+from auto_gptq.eval_tasks import SequenceClassificationTask
+
+
+MODEL = "EleutherAI/gpt-j-6b"
+DATASET = "cardiffnlp/tweet_sentiment_multilingual"
+TEMPLATE = "Question:What's the sentiment of the given text? Choices are {labels}.\nText: {text}\nAnswer:"
+ID2LABEL = {
+ 0: "negative",
+ 1: "neutral",
+ 2: "positive"
+}
+LABELS = list(ID2LABEL.values())
+
+
+def ds_refactor_fn(samples):
+ text_data = samples["text"]
+ label_data = samples["label"]
+
+ new_samples = {"prompt": [], "label": []}
+ for text, label in zip(text_data, label_data):
+ prompt = TEMPLATE.format(labels=LABELS, text=text)
+ new_samples["prompt"].append(prompt)
+ new_samples["label"].append(ID2LABEL[label])
+
+ return new_samples
+
+
+# model = AutoModelForCausalLM.from_pretrained(MODEL).eval().half().to("cuda:0")
+model = AutoGPTQForCausalLM.from_pretrained(MODEL, BaseQuantizeConfig())
+tokenizer = AutoTokenizer.from_pretrained(MODEL)
+
+task = SequenceClassificationTask(
+ model=model,
+ tokenizer=tokenizer,
+ classes=LABELS,
+ data_name_or_path=DATASET,
+ prompt_col_name="prompt",
+ label_col_name="label",
+ **{
+ "num_samples": 1000, # how many samples will be sampled to evaluation
+ "sample_max_len": 1024, # max tokens for each sample
+ "block_max_len": 2048, # max tokens for each data block
+ # function to load dataset, one must only accept data_name_or_path as input
+ # and return datasets.Dataset
+ "load_fn": partial(datasets.load_dataset, name="english"),
+ # function to preprocess dataset, which is used for datasets.Dataset.map,
+ # must return Dict[str, list] with only two keys: [prompt_col_name, label_col_name]
+ "preprocess_fn": ds_refactor_fn,
+ # truncate label when sample's length exceed sample_max_len
+ "truncate_prompt": False
+ }
+ )
+
+# note that max_new_tokens will be automatically specified internally based on given classes
+print(task.run())
+
+# self-consistency
+print(
+ task.run(
+ generation_config=GenerationConfig(
+ num_beams=3,
+ num_return_sequences=3,
+ do_sample=True
+ )
+ )
+)
+```
+
+
+
+## 了解更多
+[教程](docs/tutorial) 提供了将 `auto_gptq` 集成到你的项目中的手把手指导和最佳实践准则。
+
+[示例](examples/README.md) 提供了大量示例脚本以将 `auto_gptq` 用于不同领域。
+
+## 支持的模型
+
+> 你可以使用 `model.config.model_type` 来对照下表以检查你正在使用的一个模型是否被 `auto_gptq` 所支持。
+>
+> 比如, `WizardLM`,`vicuna` 和 `gpt4all` 模型的 `model_type` 皆为 `llama`, 因此这些模型皆被 `auto_gptq` 所支持。
+
+| model type | quantization | inference | peft-lora | peft-ada-lora | peft-adaption_prompt |
+|------------------------------------|--------------|-----------|-----------|---------------|-----------------------------------------------------------------------------------|
+| bloom | ✅ | ✅ | ✅ | ✅ | |
+| gpt2 | ✅ | ✅ | ✅ | ✅ | |
+| gpt_neox | ✅ | ✅ | ✅ | ✅ | ✅[要求该分支的 peft](https://github.com/PanQiWei/peft/tree/multi_modal_adaption_prompt) |
+| gptj | ✅ | ✅ | ✅ | ✅ | ✅[要求该分支的 peft](https://github.com/PanQiWei/peft/tree/multi_modal_adaption_prompt) |
+| llama | ✅ | ✅ | ✅ | ✅ | ✅ |
+| moss | ✅ | ✅ | ✅ | ✅ | ✅[要求该分支的 peft](https://github.com/PanQiWei/peft/tree/multi_modal_adaption_prompt) |
+| opt | ✅ | ✅ | ✅ | ✅ | |
+| gpt_bigcode | ✅ | ✅ | ✅ | ✅ | |
+| codegen | ✅ | ✅ | ✅ | ✅ | |
+| falcon(RefinedWebModel/RefinedWeb) | ✅ | ✅ | ✅ | ✅ | |
+
+## 支持的评估任务
+目前, `auto_gptq` 支持以下评估任务: `LanguageModelingTask`, `SequenceClassificationTask` 和 `TextSummarizationTask`;更多的评估任务即将到来!
+
+## 致谢
+- 特别感谢 **Elias Frantar**, **Saleh Ashkboos**, **Torsten Hoefler** 和 **Dan Alistarh** 提出 **GPTQ** 算法并开源[代码](https://github.com/IST-DASLab/gptq)。
+- 特别感谢 **qwopqwop200**, 本项目中涉及到模型量化的代码主要参考自 [GPTQ-for-LLaMa](https://github.com/qwopqwop200/GPTQ-for-LLaMa/tree/cuda)。
+
+[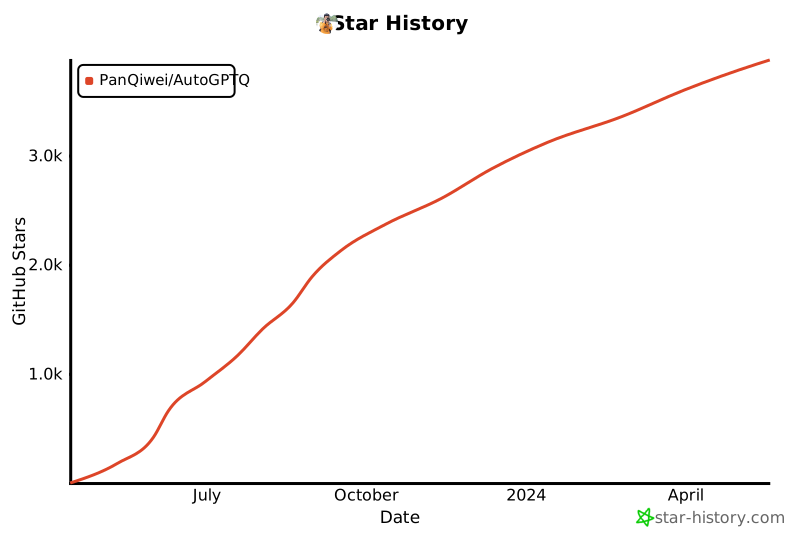](https://star-history.com/#PanQiWei/AutoGPTQ&Date)
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq.egg-info/PKG-INFO b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq.egg-info/PKG-INFO
new file mode 100644
index 0000000000000000000000000000000000000000..11026e4c1a064a4b1bbc71f5d2314249586674ab
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq.egg-info/PKG-INFO
@@ -0,0 +1,358 @@
+Metadata-Version: 2.1
+Name: auto-gptq
+Version: 0.8.0.dev0+cu124
+Summary: An easy-to-use LLMs quantization package with user-friendly apis, based on GPTQ algorithm.
+Home-page: https://github.com/PanQiWei/AutoGPTQ
+Author: PanQiWei
+Keywords: gptq,quantization,large-language-models,transformers
+Platform: windows
+Platform: linux
+Classifier: Environment :: GPU :: NVIDIA CUDA :: 11.7
+Classifier: Environment :: GPU :: NVIDIA CUDA :: 11.8
+Classifier: Environment :: GPU :: NVIDIA CUDA :: 12
+Classifier: License :: OSI Approved :: MIT License
+Classifier: Natural Language :: Chinese (Simplified)
+Classifier: Natural Language :: English
+Classifier: Programming Language :: Python :: 3.8
+Classifier: Programming Language :: Python :: 3.9
+Classifier: Programming Language :: Python :: 3.10
+Classifier: Programming Language :: Python :: 3.11
+Classifier: Programming Language :: C++
+Requires-Python: >=3.8.0
+Description-Content-Type: text/markdown
+Provides-Extra: triton
+Provides-Extra: test
+Provides-Extra: quality
+License-File: LICENSE
+
+AutoGPTQ
+An easy-to-use LLM quantization package with user-friendly APIs, based on GPTQ algorithm (weight-only quantization).
+
+
+
+
+
+
+
+
+
+
+ English |
+ 中文
+
+
+
+## News or Update
+
+- 2024-02-15 - (News) - AutoGPTQ 0.7.0 is released, with [Marlin](https://github.com/IST-DASLab/marlin) int4*fp16 matrix multiplication kernel support, with the argument `use_marlin=True` when loading models.
+- 2023-08-23 - (News) - 🤗 Transformers, optimum and peft have integrated `auto-gptq`, so now running and training GPTQ models can be more available to everyone! See [this blog](https://huggingface.co/blog/gptq-integration) and it's resources for more details!
+
+*For more histories please turn to [here](docs/NEWS_OR_UPDATE.md)*
+
+## Performance Comparison
+
+### Inference Speed
+> The result is generated using [this script](examples/benchmark/generation_speed.py), batch size of input is 1, decode strategy is beam search and enforce the model to generate 512 tokens, speed metric is tokens/s (the larger, the better).
+>
+> The quantized model is loaded using the setup that can gain the fastest inference speed.
+
+| model | GPU | num_beams | fp16 | gptq-int4 |
+|---------------|---------------|-----------|-------|-----------|
+| llama-7b | 1xA100-40G | 1 | 18.87 | 25.53 |
+| llama-7b | 1xA100-40G | 4 | 68.79 | 91.30 |
+| moss-moon 16b | 1xA100-40G | 1 | 12.48 | 15.25 |
+| moss-moon 16b | 1xA100-40G | 4 | OOM | 42.67 |
+| moss-moon 16b | 2xA100-40G | 1 | 06.83 | 06.78 |
+| moss-moon 16b | 2xA100-40G | 4 | 13.10 | 10.80 |
+| gpt-j 6b | 1xRTX3060-12G | 1 | OOM | 29.55 |
+| gpt-j 6b | 1xRTX3060-12G | 4 | OOM | 47.36 |
+
+
+### Perplexity
+For perplexity comparison, you can turn to [here](https://github.com/qwopqwop200/GPTQ-for-LLaMa#result) and [here](https://github.com/qwopqwop200/GPTQ-for-LLaMa#gptq-vs-bitsandbytes)
+
+## Installation
+
+AutoGPTQ is available on Linux and Windows only. You can install the latest stable release of AutoGPTQ from pip with pre-built wheels:
+
+| CUDA/ROCm version | Installation | Built against PyTorch |
+|-------------------|---------------------------------------------------------------------------------------------------|-----------------------|
+| CUDA 11.8 | `pip install auto-gptq --no-build-isolation --extra-index-url https://huggingface.github.io/autogptq-index/whl/cu118/` | 2.2.1+cu118 |
+| CUDA 12.1 | `pip install auto-gptq --no-build-isolation` | 2.2.1+cu121 |
+| ROCm 5.7 | `pip install auto-gptq --no-build-isolation --extra-index-url https://huggingface.github.io/autogptq-index/whl/rocm573/` | 2.2.1+rocm5.7 |
+
+AutoGPTQ can be installed with the Triton dependency with `pip install auto-gptq[triton] --no-build-isolation` in order to be able to use the Triton backend (currently only supports linux, no 3-bits quantization).
+
+For older AutoGPTQ, please refer to [the previous releases installation table](docs/INSTALLATION.md).
+
+On NVIDIA systems, AutoGPTQ does not support [Maxwell or lower](https://qiita.com/uyuni/items/733a93b975b524f89f46) GPUs.
+
+### Install from source
+
+Clone the source code:
+```bash
+git clone https://github.com/PanQiWei/AutoGPTQ.git && cd AutoGPTQ
+```
+
+A few packages are required in order to build from source: `pip install numpy gekko pandas`.
+
+Then, install locally from source:
+```bash
+pip install -vvv --no-build-isolation -e .
+```
+You can set `BUILD_CUDA_EXT=0` to disable pytorch extension building, but this is **strongly discouraged** as AutoGPTQ then falls back on a slow python implementation.
+
+As a last resort, if the above command fails, you can try `python setup.py install`.
+
+#### On ROCm systems
+
+To install from source for AMD GPUs supporting ROCm, please specify the `ROCM_VERSION` environment variable. Example:
+
+```bash
+ROCM_VERSION=5.6 pip install -vvv --no-build-isolation -e .
+```
+
+The compilation can be speeded up by specifying the `PYTORCH_ROCM_ARCH` variable ([reference](https://github.com/pytorch/pytorch/blob/7b73b1e8a73a1777ebe8d2cd4487eb13da55b3ba/setup.py#L132)) in order to build for a single target device, for example `gfx90a` for MI200 series devices.
+
+For ROCm systems, the packages `rocsparse-dev`, `hipsparse-dev`, `rocthrust-dev`, `rocblas-dev` and `hipblas-dev` are required to build.
+
+## Quick Tour
+
+### Quantization and Inference
+> warning: this is just a showcase of the usage of basic apis in AutoGPTQ, which uses only one sample to quantize a much small model, quality of quantized model using such little samples may not good.
+
+Below is an example for the simplest use of `auto_gptq` to quantize a model and inference after quantization:
+```python
+from transformers import AutoTokenizer, TextGenerationPipeline
+from auto_gptq import AutoGPTQForCausalLM, BaseQuantizeConfig
+import logging
+
+logging.basicConfig(
+ format="%(asctime)s %(levelname)s [%(name)s] %(message)s", level=logging.INFO, datefmt="%Y-%m-%d %H:%M:%S"
+)
+
+pretrained_model_dir = "facebook/opt-125m"
+quantized_model_dir = "opt-125m-4bit"
+
+tokenizer = AutoTokenizer.from_pretrained(pretrained_model_dir, use_fast=True)
+examples = [
+ tokenizer(
+ "auto-gptq is an easy-to-use model quantization library with user-friendly apis, based on GPTQ algorithm."
+ )
+]
+
+quantize_config = BaseQuantizeConfig(
+ bits=4, # quantize model to 4-bit
+ group_size=128, # it is recommended to set the value to 128
+ desc_act=False, # set to False can significantly speed up inference but the perplexity may slightly bad
+)
+
+# load un-quantized model, by default, the model will always be loaded into CPU memory
+model = AutoGPTQForCausalLM.from_pretrained(pretrained_model_dir, quantize_config)
+
+# quantize model, the examples should be list of dict whose keys can only be "input_ids" and "attention_mask"
+model.quantize(examples)
+
+# save quantized model
+model.save_quantized(quantized_model_dir)
+
+# save quantized model using safetensors
+model.save_quantized(quantized_model_dir, use_safetensors=True)
+
+# push quantized model to Hugging Face Hub.
+# to use use_auth_token=True, Login first via huggingface-cli login.
+# or pass explcit token with: use_auth_token="hf_xxxxxxx"
+# (uncomment the following three lines to enable this feature)
+# repo_id = f"YourUserName/{quantized_model_dir}"
+# commit_message = f"AutoGPTQ model for {pretrained_model_dir}: {quantize_config.bits}bits, gr{quantize_config.group_size}, desc_act={quantize_config.desc_act}"
+# model.push_to_hub(repo_id, commit_message=commit_message, use_auth_token=True)
+
+# alternatively you can save and push at the same time
+# (uncomment the following three lines to enable this feature)
+# repo_id = f"YourUserName/{quantized_model_dir}"
+# commit_message = f"AutoGPTQ model for {pretrained_model_dir}: {quantize_config.bits}bits, gr{quantize_config.group_size}, desc_act={quantize_config.desc_act}"
+# model.push_to_hub(repo_id, save_dir=quantized_model_dir, use_safetensors=True, commit_message=commit_message, use_auth_token=True)
+
+# load quantized model to the first GPU
+model = AutoGPTQForCausalLM.from_quantized(quantized_model_dir, device="cuda:0")
+
+# download quantized model from Hugging Face Hub and load to the first GPU
+# model = AutoGPTQForCausalLM.from_quantized(repo_id, device="cuda:0", use_safetensors=True, use_triton=False)
+
+# inference with model.generate
+print(tokenizer.decode(model.generate(**tokenizer("auto_gptq is", return_tensors="pt").to(model.device))[0]))
+
+# or you can also use pipeline
+pipeline = TextGenerationPipeline(model=model, tokenizer=tokenizer)
+print(pipeline("auto-gptq is")[0]["generated_text"])
+```
+
+For more advanced features of model quantization, please reference to [this script](examples/quantization/quant_with_alpaca.py)
+
+### Customize Model
+
+
+Below is an example to extend `auto_gptq` to support `OPT` model, as you will see, it's very easy:
+
+```python
+from auto_gptq.modeling import BaseGPTQForCausalLM
+
+
+class OPTGPTQForCausalLM(BaseGPTQForCausalLM):
+ # chained attribute name of transformer layer block
+ layers_block_name = "model.decoder.layers"
+ # chained attribute names of other nn modules that in the same level as the transformer layer block
+ outside_layer_modules = [
+ "model.decoder.embed_tokens", "model.decoder.embed_positions", "model.decoder.project_out",
+ "model.decoder.project_in", "model.decoder.final_layer_norm"
+ ]
+ # chained attribute names of linear layers in transformer layer module
+ # normally, there are four sub lists, for each one the modules in it can be seen as one operation,
+ # and the order should be the order when they are truly executed, in this case (and usually in most cases),
+ # they are: attention q_k_v projection, attention output projection, MLP project input, MLP project output
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.out_proj"],
+ ["fc1"],
+ ["fc2"]
+ ]
+```
+After this, you can use `OPTGPTQForCausalLM.from_pretrained` and other methods as shown in Basic.
+
+
+
+### Evaluation on Downstream Tasks
+You can use tasks defined in `auto_gptq.eval_tasks` to evaluate model's performance on specific down-stream task before and after quantization.
+
+The predefined tasks support all causal-language-models implemented in [🤗 transformers](https://github.com/huggingface/transformers) and in this project.
+
+
+
+Below is an example to evaluate `EleutherAI/gpt-j-6b` on sequence-classification task using `cardiffnlp/tweet_sentiment_multilingual` dataset:
+
+```python
+from functools import partial
+
+import datasets
+from transformers import AutoTokenizer, AutoModelForCausalLM, GenerationConfig
+
+from auto_gptq import AutoGPTQForCausalLM, BaseQuantizeConfig
+from auto_gptq.eval_tasks import SequenceClassificationTask
+
+
+MODEL = "EleutherAI/gpt-j-6b"
+DATASET = "cardiffnlp/tweet_sentiment_multilingual"
+TEMPLATE = "Question:What's the sentiment of the given text? Choices are {labels}.\nText: {text}\nAnswer:"
+ID2LABEL = {
+ 0: "negative",
+ 1: "neutral",
+ 2: "positive"
+}
+LABELS = list(ID2LABEL.values())
+
+
+def ds_refactor_fn(samples):
+ text_data = samples["text"]
+ label_data = samples["label"]
+
+ new_samples = {"prompt": [], "label": []}
+ for text, label in zip(text_data, label_data):
+ prompt = TEMPLATE.format(labels=LABELS, text=text)
+ new_samples["prompt"].append(prompt)
+ new_samples["label"].append(ID2LABEL[label])
+
+ return new_samples
+
+
+# model = AutoModelForCausalLM.from_pretrained(MODEL).eval().half().to("cuda:0")
+model = AutoGPTQForCausalLM.from_pretrained(MODEL, BaseQuantizeConfig())
+tokenizer = AutoTokenizer.from_pretrained(MODEL)
+
+task = SequenceClassificationTask(
+ model=model,
+ tokenizer=tokenizer,
+ classes=LABELS,
+ data_name_or_path=DATASET,
+ prompt_col_name="prompt",
+ label_col_name="label",
+ **{
+ "num_samples": 1000, # how many samples will be sampled to evaluation
+ "sample_max_len": 1024, # max tokens for each sample
+ "block_max_len": 2048, # max tokens for each data block
+ # function to load dataset, one must only accept data_name_or_path as input
+ # and return datasets.Dataset
+ "load_fn": partial(datasets.load_dataset, name="english"),
+ # function to preprocess dataset, which is used for datasets.Dataset.map,
+ # must return Dict[str, list] with only two keys: [prompt_col_name, label_col_name]
+ "preprocess_fn": ds_refactor_fn,
+ # truncate label when sample's length exceed sample_max_len
+ "truncate_prompt": False
+ }
+ )
+
+# note that max_new_tokens will be automatically specified internally based on given classes
+print(task.run())
+
+# self-consistency
+print(
+ task.run(
+ generation_config=GenerationConfig(
+ num_beams=3,
+ num_return_sequences=3,
+ do_sample=True
+ )
+ )
+)
+```
+
+
+
+## Learn More
+[tutorials](docs/tutorial) provide step-by-step guidance to integrate `auto_gptq` with your own project and some best practice principles.
+
+[examples](examples/README.md) provide plenty of example scripts to use `auto_gptq` in different ways.
+
+## Supported Models
+
+> you can use `model.config.model_type` to compare with the table below to check whether the model you use is supported by `auto_gptq`.
+>
+> for example, model_type of `WizardLM`, `vicuna` and `gpt4all` are all `llama`, hence they are all supported by `auto_gptq`.
+
+| model type | quantization | inference | peft-lora | peft-ada-lora | peft-adaption_prompt |
+|------------------------------------|--------------|-----------|-----------|---------------|-------------------------------------------------------------------------------------------------|
+| bloom | ✅ | ✅ | ✅ | ✅ | |
+| gpt2 | ✅ | ✅ | ✅ | ✅ | |
+| gpt_neox | ✅ | ✅ | ✅ | ✅ | ✅[requires this peft branch](https://github.com/PanQiWei/peft/tree/multi_modal_adaption_prompt) |
+| gptj | ✅ | ✅ | ✅ | ✅ | ✅[requires this peft branch](https://github.com/PanQiWei/peft/tree/multi_modal_adaption_prompt) |
+| llama | ✅ | ✅ | ✅ | ✅ | ✅ |
+| moss | ✅ | ✅ | ✅ | ✅ | ✅[requires this peft branch](https://github.com/PanQiWei/peft/tree/multi_modal_adaption_prompt) |
+| opt | ✅ | ✅ | ✅ | ✅ | |
+| gpt_bigcode | ✅ | ✅ | ✅ | ✅ | |
+| codegen | ✅ | ✅ | ✅ | ✅ | |
+| falcon(RefinedWebModel/RefinedWeb) | ✅ | ✅ | ✅ | ✅ | |
+
+## Supported Evaluation Tasks
+Currently, `auto_gptq` supports: `LanguageModelingTask`, `SequenceClassificationTask` and `TextSummarizationTask`; more Tasks will come soon!
+
+## Running tests
+
+Tests can be run with:
+
+```
+pytest tests/ -s
+```
+
+## FAQ
+
+### Which kernel is used by default?
+
+AutoGPTQ defaults to using exllamav2 int4*fp16 kernel for matrix multiplication.
+
+### How to use Marlin kernel?
+
+Marlin is an optimized int4 * fp16 kernel was recently proposed at https://github.com/IST-DASLab/marlin. This is integrated in AutoGPTQ when loading a model with `use_marlin=True`. This kernel is available only on devices with compute capability 8.0 or 8.6 (Ampere GPUs).
+
+## Acknowledgement
+- Special thanks **Elias Frantar**, **Saleh Ashkboos**, **Torsten Hoefler** and **Dan Alistarh** for proposing **GPTQ** algorithm and open source the [code](https://github.com/IST-DASLab/gptq), and for releasing [Marlin kernel](https://github.com/IST-DASLab/marlin) for mixed precision computation.
+- Special thanks **qwopqwop200**, for code in this project that relevant to quantization are mainly referenced from [GPTQ-for-LLaMa](https://github.com/qwopqwop200/GPTQ-for-LLaMa/tree/cuda).
+- Special thanks to **turboderp**, for releasing [Exllama](https://github.com/turboderp/exllama) and [Exllama v2](https://github.com/turboderp/exllamav2) libraries with efficient mixed precision kernels.
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq.egg-info/SOURCES.txt b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq.egg-info/SOURCES.txt
new file mode 100644
index 0000000000000000000000000000000000000000..2e9baed8728a74e919a2469da8770c541b7aa154
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq.egg-info/SOURCES.txt
@@ -0,0 +1,138 @@
+LICENSE
+MANIFEST.in
+README.md
+setup.py
+auto_gptq/__init__.py
+auto_gptq.egg-info/PKG-INFO
+auto_gptq.egg-info/SOURCES.txt
+auto_gptq.egg-info/dependency_links.txt
+auto_gptq.egg-info/requires.txt
+auto_gptq.egg-info/top_level.txt
+auto_gptq/eval_tasks/__init__.py
+auto_gptq/eval_tasks/_base.py
+auto_gptq/eval_tasks/language_modeling_task.py
+auto_gptq/eval_tasks/sequence_classification_task.py
+auto_gptq/eval_tasks/text_summarization_task.py
+auto_gptq/eval_tasks/_utils/__init__.py
+auto_gptq/eval_tasks/_utils/classification_utils.py
+auto_gptq/eval_tasks/_utils/generation_utils.py
+auto_gptq/modeling/__init__.py
+auto_gptq/modeling/_base.py
+auto_gptq/modeling/_const.py
+auto_gptq/modeling/_utils.py
+auto_gptq/modeling/auto.py
+auto_gptq/modeling/baichuan.py
+auto_gptq/modeling/bloom.py
+auto_gptq/modeling/codegen.py
+auto_gptq/modeling/cohere.py
+auto_gptq/modeling/decilm.py
+auto_gptq/modeling/gemma.py
+auto_gptq/modeling/gpt2.py
+auto_gptq/modeling/gpt_bigcode.py
+auto_gptq/modeling/gpt_neox.py
+auto_gptq/modeling/gptj.py
+auto_gptq/modeling/internlm.py
+auto_gptq/modeling/llama.py
+auto_gptq/modeling/longllama.py
+auto_gptq/modeling/mistral.py
+auto_gptq/modeling/mixtral.py
+auto_gptq/modeling/moss.py
+auto_gptq/modeling/mpt.py
+auto_gptq/modeling/opt.py
+auto_gptq/modeling/phi.py
+auto_gptq/modeling/qwen.py
+auto_gptq/modeling/qwen2.py
+auto_gptq/modeling/rw.py
+auto_gptq/modeling/stablelmepoch.py
+auto_gptq/modeling/starcoder2.py
+auto_gptq/modeling/xverse.py
+auto_gptq/modeling/yi.py
+auto_gptq/nn_modules/__init__.py
+auto_gptq/nn_modules/_fused_base.py
+auto_gptq/nn_modules/fused_gptj_attn.py
+auto_gptq/nn_modules/fused_llama_attn.py
+auto_gptq/nn_modules/fused_llama_mlp.py
+auto_gptq/nn_modules/qlinear/__init__.py
+auto_gptq/nn_modules/qlinear/qlinear_cuda.py
+auto_gptq/nn_modules/qlinear/qlinear_cuda_old.py
+auto_gptq/nn_modules/qlinear/qlinear_exllama.py
+auto_gptq/nn_modules/qlinear/qlinear_exllamav2.py
+auto_gptq/nn_modules/qlinear/qlinear_marlin.py
+auto_gptq/nn_modules/qlinear/qlinear_qigen.py
+auto_gptq/nn_modules/qlinear/qlinear_triton.py
+auto_gptq/nn_modules/qlinear/qlinear_tritonv2.py
+auto_gptq/nn_modules/triton_utils/__init__.py
+auto_gptq/nn_modules/triton_utils/custom_autotune.py
+auto_gptq/nn_modules/triton_utils/dequant.py
+auto_gptq/nn_modules/triton_utils/kernels.py
+auto_gptq/nn_modules/triton_utils/mixin.py
+auto_gptq/quantization/__init__.py
+auto_gptq/quantization/config.py
+auto_gptq/quantization/gptq.py
+auto_gptq/quantization/quantizer.py
+auto_gptq/utils/__init__.py
+auto_gptq/utils/accelerate_utils.py
+auto_gptq/utils/data_utils.py
+auto_gptq/utils/exllama_utils.py
+auto_gptq/utils/import_utils.py
+auto_gptq/utils/marlin_utils.py
+auto_gptq/utils/modeling_utils.py
+auto_gptq/utils/peft_utils.py
+auto_gptq/utils/perplexity_utils.py
+autogptq_extension/cuda_256/autogptq_cuda_256.cpp
+autogptq_extension/cuda_256/autogptq_cuda_kernel_256.cu
+autogptq_extension/cuda_64/autogptq_cuda_64.cpp
+autogptq_extension/cuda_64/autogptq_cuda_kernel_64.cu
+autogptq_extension/exllama/cu_compat.cuh
+autogptq_extension/exllama/cuda_buffers.cu
+autogptq_extension/exllama/cuda_buffers.cuh
+autogptq_extension/exllama/exllama_ext.cpp
+autogptq_extension/exllama/hip_compat.cuh
+autogptq_extension/exllama/matrix.cuh
+autogptq_extension/exllama/tuning.h
+autogptq_extension/exllama/util.cuh
+autogptq_extension/exllama/cuda_func/column_remap.cu
+autogptq_extension/exllama/cuda_func/column_remap.cuh
+autogptq_extension/exllama/cuda_func/q4_matmul.cu
+autogptq_extension/exllama/cuda_func/q4_matmul.cuh
+autogptq_extension/exllama/cuda_func/q4_matrix.cu
+autogptq_extension/exllama/cuda_func/q4_matrix.cuh
+autogptq_extension/exllamav2/config.h
+autogptq_extension/exllamav2/ext.cpp
+autogptq_extension/exllamav2/cpp/util.h
+autogptq_extension/exllamav2/cuda/compat.cuh
+autogptq_extension/exllamav2/cuda/compat_gemm.cuh
+autogptq_extension/exllamav2/cuda/matrix_view.cuh
+autogptq_extension/exllamav2/cuda/q_gemm.cu
+autogptq_extension/exllamav2/cuda/q_gemm.cuh
+autogptq_extension/exllamav2/cuda/q_gemm_kernel.cuh
+autogptq_extension/exllamav2/cuda/q_gemm_kernel_gptq.cuh
+autogptq_extension/exllamav2/cuda/q_matrix.cu
+autogptq_extension/exllamav2/cuda/q_matrix.cuh
+autogptq_extension/exllamav2/cuda/util.cuh
+autogptq_extension/exllamav2/cuda/quant/qdq_2.cuh
+autogptq_extension/exllamav2/cuda/quant/qdq_3.cuh
+autogptq_extension/exllamav2/cuda/quant/qdq_4.cuh
+autogptq_extension/exllamav2/cuda/quant/qdq_5.cuh
+autogptq_extension/exllamav2/cuda/quant/qdq_6.cuh
+autogptq_extension/exllamav2/cuda/quant/qdq_8.cuh
+autogptq_extension/exllamav2/cuda/quant/qdq_util.cuh
+autogptq_extension/marlin/marlin_cuda.cpp
+autogptq_extension/marlin/marlin_cuda_kernel.cu
+autogptq_extension/marlin/marlin_cuda_kernel.cuh
+autogptq_extension/marlin/marlin_repack.cu
+autogptq_extension/marlin/marlin_repack.cuh
+autogptq_extension/qigen/generate.py
+autogptq_extension/qigen/intrin.py
+autogptq_extension/qigen/mmm.cpp
+autogptq_extension/qigen/template.py
+tests/__init__.py
+tests/bench_autoawq_autogptq.py
+tests/test_awq_compatibility_generation.py
+tests/test_peft_conversion.py
+tests/test_q4.py
+tests/test_quantization.py
+tests/test_repacking.py
+tests/test_serialization.py
+tests/test_sharded_loading.py
+tests/test_triton.py
\ No newline at end of file
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq.egg-info/dependency_links.txt b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq.egg-info/dependency_links.txt
new file mode 100644
index 0000000000000000000000000000000000000000..8b137891791fe96927ad78e64b0aad7bded08bdc
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq.egg-info/dependency_links.txt
@@ -0,0 +1 @@
+
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq.egg-info/requires.txt b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq.egg-info/requires.txt
new file mode 100644
index 0000000000000000000000000000000000000000..12bc1b77abba3dff8dce794085d279e09401a35b
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq.egg-info/requires.txt
@@ -0,0 +1,21 @@
+accelerate>=0.26.0
+datasets
+sentencepiece
+numpy
+rouge
+gekko
+torch>=1.13.0
+safetensors
+transformers>=4.31.0
+peft>=0.5.0
+tqdm
+
+[quality]
+ruff==0.1.5
+
+[test]
+pytest
+parameterized
+
+[triton]
+triton==2.0.0
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq.egg-info/top_level.txt b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq.egg-info/top_level.txt
new file mode 100644
index 0000000000000000000000000000000000000000..6316fbb4247980710e9fe2bacb8769ecef84ff41
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq.egg-info/top_level.txt
@@ -0,0 +1,7 @@
+auto_gptq
+autogptq_cuda_256
+autogptq_cuda_64
+autogptq_marlin_cuda
+exllama_kernels
+exllamav2_kernels
+tests
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/__init__.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..cf1c2a9e838781b0bada877f87a6362f0b83d14a
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/__init__.py
@@ -0,0 +1,6 @@
+from .modeling import AutoGPTQForCausalLM, BaseQuantizeConfig
+from .utils.exllama_utils import exllama_set_max_input_length
+from .utils.peft_utils import get_gptq_peft_model
+
+
+__version__ = "0.8.0.dev0"
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/__init__.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..ac0e178f11e52e46afa2b0ead26e8f9ed0ae4cdd
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/__init__.py
@@ -0,0 +1,3 @@
+from .language_modeling_task import LanguageModelingTask
+from .sequence_classification_task import SequenceClassificationTask, get_predictions
+from .text_summarization_task import TextSummarizationTask
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/_base.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/_base.py
new file mode 100644
index 0000000000000000000000000000000000000000..1bb3be2e430b680e02ce17cdff58626286b3bab2
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/_base.py
@@ -0,0 +1,65 @@
+from abc import abstractmethod
+from typing import Any, Dict, List, Optional, Union
+
+import torch
+from transformers import PreTrainedModel, PreTrainedTokenizer
+
+from ..modeling import BaseGPTQForCausalLM
+from ..utils.data_utils import get_dataloader
+
+
+class BaseTask:
+ def __init__(
+ self,
+ model: Union[BaseGPTQForCausalLM, PreTrainedModel],
+ tokenizer: PreTrainedTokenizer,
+ data_name_or_path: str,
+ prompt_col_name: str,
+ label_col_name: str,
+ device: Optional[str] = None,
+ **kwargs,
+ ):
+ self.model = model
+ self.tokenizer = tokenizer
+ if self.tokenizer.pad_token_id is None:
+ self.tokenizer.pad_token = self.tokenizer.eos_token
+ self.tokenizer.pad_token_id = self.tokenizer.eos_token_id
+ self.model.config.pad_token_id = self.tokenizer.eos_token_id
+ self.dl = get_dataloader(
+ data_name_or_path,
+ prompt_col_name=prompt_col_name,
+ label_col_name=label_col_name,
+ tokenizer=tokenizer,
+ **kwargs,
+ )
+
+ self.device = device
+ if not self.device:
+ self.device = self.model.device
+ if isinstance(self.device, str):
+ self.device = torch.device(self.device)
+
+ @abstractmethod
+ def _predict(self, batch_data: Dict[str, Any], **kwargs) -> List[Any]:
+ pass
+
+ @abstractmethod
+ def _parse_labels(self, label_ids: torch.LongTensor) -> List[Any]:
+ pass
+
+ @abstractmethod
+ def _metric(self, pred: List[Any], label: List[Any]) -> Dict[str, float]:
+ pass
+
+ def run(self, **predict_kwargs) -> Dict[str, float]:
+ with torch.inference_mode(), torch.amp.autocast(device_type=self.device.type):
+ predictions = []
+ labels = []
+ for batch_data in self.dl:
+ for k, v in batch_data.items():
+ if isinstance(v, torch.Tensor):
+ batch_data[k] = v.to(self.device)
+ labels += self._parse_labels(batch_data["labels"])
+ predictions += self._predict(batch_data, **predict_kwargs)
+
+ return self._metric(predictions, labels)
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/_utils/__init__.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/_utils/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/_utils/classification_utils.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/_utils/classification_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..9cf5e6af92250ed3426eecce72b53fc298361e7d
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/_utils/classification_utils.py
@@ -0,0 +1,44 @@
+import sys
+from typing import List, Sequence
+
+import numpy as np
+
+
+def levenshtein_distance(seq1: Sequence, seq2: Sequence):
+ if seq1 == seq2:
+ return 0
+ num_rows = len(seq1) + 1
+ num_cols = len(seq2) + 1
+ dp_matrix = np.empty((num_rows, num_cols))
+ dp_matrix[0, :] = range(num_cols)
+ dp_matrix[:, 0] = range(num_rows)
+
+ for i in range(1, num_rows):
+ for j in range(1, num_cols):
+ if seq1[i - 1] == seq2[j - 1]:
+ dp_matrix[i, j] = dp_matrix[i - 1, j - 1]
+ else:
+ dp_matrix[i, j] = (
+ min(
+ dp_matrix[i - 1, j - 1],
+ dp_matrix[i - 1, j],
+ dp_matrix[i, j - 1],
+ )
+ + 1
+ )
+
+ return dp_matrix[num_rows - 1, num_cols - 1]
+
+
+def get_closest_label(pred: Sequence, classes: List[Sequence]) -> int:
+ min_id = sys.maxsize
+ min_edit_distance = sys.maxsize
+ for i, class_label in enumerate(classes):
+ edit_distance = levenshtein_distance(pred, class_label)
+ if edit_distance < min_edit_distance:
+ min_id = i
+ min_edit_distance = edit_distance
+ return min_id
+
+
+__all__ = ["levenshtein_distance", "get_closest_label"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/_utils/generation_utils.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/_utils/generation_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..0c5dd3c5020fefaf1f7a78c334a24a1e9d2d3e57
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/_utils/generation_utils.py
@@ -0,0 +1,36 @@
+from typing import List, Optional, Union
+
+from torch import LongTensor
+from transformers import PreTrainedTokenizer
+
+
+def postprocess_generation_ids(
+ input_ids: LongTensor,
+ output_ids: LongTensor,
+ num_return_sequences: int,
+ tokenizer: Optional[PreTrainedTokenizer] = None,
+ pad_token_ids: Optional[int] = None,
+) -> List[List[Union[str, List[int]]]]:
+ outputs = []
+ for idx, start in enumerate(range(0, len(output_ids), num_return_sequences)):
+ sub_output_ids = output_ids[start : start + num_return_sequences]
+ sub_generated_ids = sub_output_ids[..., input_ids[idx].size(0) :]
+ if tokenizer:
+ decoded_bach = (
+ generated_text
+ for generated_text in tokenizer.batch_decode(sub_generated_ids, clean_up_tokenization_spaces=True)
+ )
+ decoded_bach = list(decoded_bach)
+ outputs.append(decoded_bach)
+ else:
+ sub_generated_ids = sub_output_ids.cpu().numpy().tolist()
+ for i, one_sub_generated_ids in enumerate(sub_generated_ids):
+ if pad_token_ids is not None and pad_token_ids in one_sub_generated_ids:
+ one_sub_generated_ids = one_sub_generated_ids[: one_sub_generated_ids.index(pad_token_ids)]
+ sub_generated_ids[i] = one_sub_generated_ids
+ outputs.append(sub_generated_ids)
+
+ return outputs
+
+
+__all__ = ["postprocess_generation_ids"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/language_modeling_task.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/language_modeling_task.py
new file mode 100644
index 0000000000000000000000000000000000000000..98efae77c68e4da5593f6a2d10c8b40c018cf36e
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/language_modeling_task.py
@@ -0,0 +1,47 @@
+import math
+from typing import Any, Dict, List, Optional
+
+from torch import LongTensor
+
+from ._base import BaseTask
+
+
+class LanguageModelingTask(BaseTask):
+ def __init__(
+ self,
+ model,
+ tokenizer,
+ data_name_or_path: str,
+ prompt_col_name: str,
+ label_col_name: str,
+ device: Optional[str] = None,
+ **kwargs,
+ ):
+ kwargs["merge_prompt_label"] = True
+ super().__init__(
+ model=model,
+ tokenizer=tokenizer,
+ data_name_or_path=data_name_or_path,
+ prompt_col_name=prompt_col_name,
+ label_col_name=label_col_name,
+ device=device,
+ **kwargs,
+ )
+
+ def _predict(self, batch_data: Dict[str, Any], *args, **kwargs) -> List[float]:
+ outputs = self.model(**batch_data)
+ loss = outputs.loss.cpu().item()
+
+ return [loss]
+
+ def _parse_labels(self, label_ids: LongTensor) -> List[Any]:
+ return []
+
+ def _metric(self, pred: List[Any], label: List[Any]) -> Dict[str, float]:
+ return {"ppl": math.exp(sum(pred) / len(pred))}
+
+ def run(self) -> Dict[str, float]:
+ return super().run()
+
+
+__all__ = ["LanguageModelingTask"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/sequence_classification_task.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/sequence_classification_task.py
new file mode 100644
index 0000000000000000000000000000000000000000..9de3d9b273a7352b80e6bbf91f93c7c904c1b376
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/sequence_classification_task.py
@@ -0,0 +1,103 @@
+from collections import Counter
+from typing import Any, Dict, List, Optional
+
+import numpy as np
+from torch import LongTensor
+from transformers import GenerationConfig, PreTrainedTokenizer
+
+from ._base import BaseTask
+from ._utils.classification_utils import get_closest_label
+from ._utils.generation_utils import postprocess_generation_ids
+
+
+def get_predictions(
+ input_ids: LongTensor,
+ output_ids: LongTensor,
+ num_return_sequences: int,
+ tokenizer: PreTrainedTokenizer,
+ classes: List[str],
+) -> List[int]:
+ predictions = []
+ generated_texts = postprocess_generation_ids(
+ input_ids=input_ids,
+ output_ids=output_ids,
+ num_return_sequences=num_return_sequences,
+ tokenizer=tokenizer,
+ )
+ for sub_generated_texts in generated_texts:
+ sub_predictions = []
+ for gen_text in sub_generated_texts:
+ sub_predictions.append(get_closest_label(gen_text.lower().strip(), classes))
+ predictions.append(Counter(sub_predictions).most_common(1)[0][0])
+ return predictions
+
+
+class SequenceClassificationTask(BaseTask):
+ def __init__(
+ self,
+ model,
+ tokenizer: PreTrainedTokenizer,
+ classes: List[str],
+ data_name_or_path: str,
+ prompt_col_name: str,
+ label_col_name: str,
+ device: Optional[str] = None,
+ **kwargs,
+ ):
+ kwargs["merge_prompt_label"] = False
+ super().__init__(
+ model=model,
+ tokenizer=tokenizer,
+ data_name_or_path=data_name_or_path,
+ prompt_col_name=prompt_col_name,
+ label_col_name=label_col_name,
+ device=device,
+ **kwargs,
+ )
+ self.classes = [each.lower().strip() for each in classes]
+ classes_ids = self.tokenizer(classes)
+ self.max_new_tokens = max([len(each) for each in classes_ids])
+
+ def _predict(self, batch_data: Dict[str, Any], *args, **kwargs) -> List[int]:
+ generation_config = kwargs["generation_config"]
+ output_ids = self.model.generate(
+ input_ids=batch_data["input_ids"],
+ attention_mask=batch_data["attention_mask"],
+ generation_config=generation_config,
+ )
+ return get_predictions(
+ batch_data["input_ids"],
+ output_ids,
+ generation_config.num_return_sequences,
+ self.tokenizer,
+ self.classes,
+ )
+
+ def _parse_labels(self, label_ids: LongTensor) -> List[int]:
+ labels = []
+ for one_label_ids in label_ids:
+ one_label_ids = one_label_ids[(one_label_ids == -100).sum() :]
+ label = self.tokenizer.decode(one_label_ids, clean_up_tokenization_spaces=True).lower().strip()
+ label = get_closest_label(label, self.classes)
+ labels.append(label)
+
+ return labels
+
+ def _metric(self, pred: List[int], label: List[int]) -> Dict[str, float]:
+ pred = np.array(pred)
+ label = np.array(label)
+
+ acc = (pred == label).mean()
+
+ return {"acc": acc}
+
+ def run(self, generation_config: Optional[GenerationConfig] = None) -> Dict[str, float]:
+ if not generation_config:
+ generation_config = GenerationConfig(num_beams=1, do_sample=False, num_return_sequences=1)
+ generation_config.max_new_tokens = self.max_new_tokens
+ generation_config.eos_token_id = self.tokenizer.eos_token_id
+ generation_config.pad_token_id = self.tokenizer.pad_token_id
+ return super().run(generation_config=generation_config)
+
+
+__all__ = ["SequenceClassificationTask"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/text_summarization_task.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/text_summarization_task.py
new file mode 100644
index 0000000000000000000000000000000000000000..0e02b95421a005d493bcdb9c44e1e4ef43e0f588
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/eval_tasks/text_summarization_task.py
@@ -0,0 +1,72 @@
+from typing import Any, Dict, List, Optional
+
+import rouge
+from torch import LongTensor
+from transformers import GenerationConfig
+
+from ._base import BaseTask
+from ._utils.generation_utils import postprocess_generation_ids
+
+
+class TextSummarizationTask(BaseTask):
+ def __init__(
+ self,
+ model,
+ tokenizer,
+ data_name_or_path: str,
+ prompt_col_name: str,
+ label_col_name: str,
+ device: Optional[str] = None,
+ **kwargs,
+ ):
+ kwargs["merge_prompt_label"] = False
+ super().__init__(
+ model=model,
+ tokenizer=tokenizer,
+ data_name_or_path=data_name_or_path,
+ prompt_col_name=prompt_col_name,
+ label_col_name=label_col_name,
+ device=device,
+ **kwargs,
+ )
+
+ def _predict(self, batch_data: Dict[str, Any], *args, **kwargs) -> List[str]:
+ generation_config = kwargs["generation_config"]
+ output_ids = self.model.generate(
+ input_ids=batch_data["input_ids"],
+ attention_mask=batch_data["attention_mask"],
+ generation_config=generation_config,
+ )
+ return [
+ each[0].lower().strip()
+ for each in postprocess_generation_ids(
+ input_ids=batch_data["input_ids"],
+ output_ids=output_ids,
+ num_return_sequences=generation_config.num_return_sequences,
+ tokenizer=self.tokenizer,
+ )
+ ]
+
+ def _parse_labels(self, label_ids: LongTensor) -> List[str]:
+ labels = []
+ for one_label_ids in label_ids:
+ one_label_ids = one_label_ids[(one_label_ids == -100).sum() :]
+ label = self.tokenizer.decode(one_label_ids).lower().strip()
+ labels.append(label)
+
+ return labels
+
+ def _metric(self, pred: List[Any], label: List[Any]) -> Dict[str, Dict[str, float]]:
+ metric = rouge.Rouge()
+ return metric.get_scores(hyps=pred, refs=label, avg=True)
+
+ def run(self, generation_config: Optional[GenerationConfig] = None) -> Dict[str, float]:
+ if not generation_config:
+ generation_config = GenerationConfig(num_beams=1, do_sample=False, max_new_tokens=128)
+ generation_config.num_return_sequences = 1
+ generation_config.eos_token_id = self.tokenizer.eos_token_id
+ generation_config.pad_token_id = self.tokenizer.pad_token_id
+ return super().run(generation_config=generation_config)
+
+
+__all__ = ["TextSummarizationTask"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/__init__.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..ff0bcad3f512b68d02585c314e9da0b35b104279
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/__init__.py
@@ -0,0 +1,28 @@
+from ._base import BaseGPTQForCausalLM, BaseQuantizeConfig
+from .auto import GPTQ_CAUSAL_LM_MODEL_MAP, AutoGPTQForCausalLM
+from .baichuan import BaiChuanGPTQForCausalLM
+from .bloom import BloomGPTQForCausalLM
+from .codegen import CodeGenGPTQForCausalLM
+from .cohere import CohereGPTQForCausalLM
+from .decilm import DeciLMGPTQForCausalLM
+from .gemma import GemmaGPTQForCausalLM
+from .gpt2 import GPT2GPTQForCausalLM
+from .gpt_bigcode import GPTBigCodeGPTQForCausalLM
+from .gpt_neox import GPTNeoXGPTQForCausalLM
+from .gptj import GPTJGPTQForCausalLM
+from .internlm import InternLMGPTQForCausalLM
+from .llama import LlamaGPTQForCausalLM
+from .longllama import LongLlamaGPTQForCausalLM
+from .mistral import MistralGPTQForCausalLM
+from .mixtral import MixtralGPTQForCausalLM
+from .moss import MOSSGPTQForCausalLM
+from .mpt import MPTGPTQForCausalLM
+from .opt import OPTGPTQForCausalLM
+from .phi import PhiGPTQForCausalLM
+from .qwen import QwenGPTQForCausalLM
+from .qwen2 import Qwen2GPTQForCausalLM
+from .rw import RWGPTQForCausalLM
+from .stablelmepoch import StableLMEpochGPTQForCausalLM
+from .starcoder2 import Starcoder2GPTQForCausalLM
+from .xverse import XverseGPTQForCausalLM
+from .yi import YiGPTQForCausalLM
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/_base.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/_base.py
new file mode 100644
index 0000000000000000000000000000000000000000..885eabfa33d111b6836ea6d4ea8f1433b8b0c7d0
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/_base.py
@@ -0,0 +1,1319 @@
+import copy
+import logging
+import os
+from os.path import isdir, join
+from typing import Dict, List, Optional, Union
+
+import accelerate
+import torch
+import torch.nn as nn
+import transformers
+from accelerate.hooks import remove_hook_from_module
+from safetensors import safe_open
+from safetensors.torch import load_file as safe_load
+from safetensors.torch import save_file as safe_save
+from tqdm import tqdm
+from transformers import AutoConfig, AutoModelForCausalLM, PreTrainedModel
+from transformers.modeling_utils import no_init_weights
+from transformers.utils.generic import ContextManagers
+from transformers.utils.hub import (
+ CommitOperationAdd,
+ PushToHubMixin,
+ create_commit,
+ create_repo,
+)
+
+from ..nn_modules._fused_base import FusedBaseAttentionModule, FusedBaseMLPModule
+from ..nn_modules.qlinear import GeneralQuantLinear
+from ..quantization import GPTQ, BaseQuantizeConfig
+from ..quantization.config import (
+ CHECKPOINT_FORMAT,
+ CHECKPOINT_FORMAT_FIELD,
+ QUANT_METHOD_FIELD,
+ QUANTIZE_BLACK_LIST,
+)
+from ..utils.accelerate_utils import load_checkpoint_in_model
+from ..utils.data_utils import collate_data
+from ..utils.import_utils import (
+ AUTOGPTQ_CUDA_AVAILABLE,
+ EXLLAMA_KERNELS_AVAILABLE,
+ EXLLAMAV2_KERNELS_AVAILABLE,
+ MARLIN_AVAILABLE,
+ QIGEN_AVAILABLE,
+ TRITON_AVAILABLE,
+ dynamically_import_QuantLinear,
+)
+from ..utils.marlin_utils import (
+ _validate_marlin_compatibility,
+ _validate_marlin_device_support,
+ prepare_model_for_marlin_load,
+)
+from ._const import CPU, CUDA_0, SUPPORTED_MODELS
+from ._utils import (
+ autogptq_post_init,
+ find_layers,
+ get_checkpoints,
+ get_device,
+ get_module_by_name_prefix,
+ get_module_by_name_suffix,
+ make_quant,
+ make_sure_no_tensor_in_meta_device,
+ move_to_device,
+ pack_from_tensors,
+ pack_model,
+ preprocess_checkpoint_qigen,
+ simple_dispatch_model,
+ unpack_awq,
+)
+
+
+logger = logging.getLogger(__name__)
+handler = logging.StreamHandler()
+formatter = logging.Formatter("%(levelname)s - %(message)s")
+handler.setFormatter(formatter)
+logger.propagate = False
+logger.addHandler(handler)
+logger.setLevel(logging.INFO)
+
+
+def nested_move_to_device(v, device):
+ if isinstance(v, torch.Tensor):
+ return move_to_device(v, device)
+ elif isinstance(v, (list, tuple)):
+ return type(v)([nested_move_to_device(e, device) for e in v])
+ else:
+ return v
+
+
+class BaseGPTQForCausalLM(nn.Module, PushToHubMixin):
+ layer_type: str = None
+ layers_block_name: str = None
+ outside_layer_modules: List[str] = None
+ inside_layer_modules: List[List[str]] = None
+ lm_head_name: str = "lm_head"
+
+ fused_attn_module_type: Optional[FusedBaseAttentionModule] = None
+ fused_mlp_module_type: Optional[FusedBaseMLPModule] = None
+
+ def __init__(
+ self,
+ model: PreTrainedModel,
+ quantized: bool,
+ quantize_config: BaseQuantizeConfig,
+ is_triton_backend: bool = False,
+ injected_fused_attention: bool = False,
+ injected_fused_mlp: bool = False,
+ trainable: bool = False,
+ ):
+ super().__init__()
+
+ self.model = model
+ self.model_type = self.model.config.model_type
+ self._quantized = quantized
+ self.quantize_config = quantize_config
+ self.config = self.model.config
+
+ self.is_triton_backend = is_triton_backend
+ self.injected_fused_attention = injected_fused_attention
+ self.injected_fused_mlp = injected_fused_mlp
+ self.trainable = trainable
+
+ @property
+ def quantized(self):
+ return self._quantized
+
+ @property
+ def hf_device_map(self):
+ return getattr(self.model, "hf_device_map", None)
+
+ def _prepare_examples_for_quantization(
+ self,
+ examples: List[Dict[str, Union[List[int], torch.LongTensor]]],
+ batch_size: int = 1,
+ ):
+ def _convert_tensor_to_list(tensor):
+ if isinstance(tensor, torch.Tensor):
+ if len(tensor.shape) == 1:
+ tensor = tensor.unsqueeze(0)
+ tensor = tensor.long()
+ return tensor.cpu().numpy().tolist()
+ return [tensor]
+
+ new_examples = []
+ for example in examples:
+ input_ids = _convert_tensor_to_list(example["input_ids"])
+ attention_mask = _convert_tensor_to_list(example["attention_mask"])
+ if "labels" in example:
+ labels = _convert_tensor_to_list(example["labels"])
+ elif "label" in example:
+ labels = _convert_tensor_to_list(example["label"])
+ elif "label_ids" in example:
+ labels = _convert_tensor_to_list(example["label_ids"])
+ else:
+ labels = copy.deepcopy(input_ids)
+ new_examples.append(
+ {
+ "input_ids": input_ids,
+ "attention_mask": attention_mask,
+ "labels": labels,
+ }
+ )
+ pad_token_id = self.config.pad_token_id
+ if not pad_token_id:
+ pad_token_id = self.config.eos_token_id
+
+ new_examples = [
+ collate_data(new_examples[start : start + batch_size], pad_token_id)
+ for start in range(0, len(new_examples), batch_size)
+ ]
+ for new_example in new_examples:
+ del new_example["labels"]
+
+ return new_examples
+
+ @torch.inference_mode()
+ def quantize(
+ self,
+ examples: List[Dict[str, Union[List[int], torch.LongTensor]]],
+ batch_size: int = 1,
+ use_triton: bool = False,
+ use_cuda_fp16: bool = True,
+ autotune_warmup_after_quantized: bool = False,
+ cache_examples_on_gpu: bool = True,
+ ):
+ if self.quantized:
+ raise EnvironmentError("can't execute quantize because the model is quantized.")
+
+ if self.quantize_config.quant_method in QUANTIZE_BLACK_LIST:
+ raise ValueError(f"Unsupported quantization operation for quant method: {self.quantize_config.quant_method}")
+
+ # alert users to limit threads so packing performance does not regress by up to ~100x
+ thread_warning = """If you have not already done so, please inject the following code at the very top of your
+quantization script so the packing stage is optimized for speed. Using too many cores may reduce packing performance.
+----
+import os
+import math
+max_threads = str(min(8, os.cpu_count()))
+os.environ['OMP_NUM_THREADS'] = max_threads
+os.environ['OPENBLAS_NUM_THREADS'] = max_threads
+os.environ['MKL_NUM_THREADS'] = max_threads
+os.environ['VECLIB_MAXIMUM_THREADS'] = max_threads
+os.environ['NUMEXPR_NUM_THREADS'] = max_threads
+os.environ['NUMEXPR_MAX_THREADS'] = max_threads
+----
+"""
+ logger.warning(thread_warning)
+
+ if use_triton and not TRITON_AVAILABLE:
+ logger.warning("triton is not installed, reset use_triton to False")
+ use_triton = False
+
+ device_map = self.hf_device_map
+ if device_map:
+ for name, device in device_map.items():
+ if device == "cpu":
+ logger.info(f"truly offloading {name} to cpu with hook.")
+ module = get_module_by_name_suffix(self.model, name)
+ remove_hook_from_module(module, recurse=True)
+ accelerate.cpu_offload_with_hook(module, CUDA_0)
+
+ layer_inputs = []
+ attention_masks = []
+ position_ids = []
+ layer_input_kwargs = []
+ layer_outputs = []
+
+ examples = self._prepare_examples_for_quantization(examples, batch_size)
+
+ forward_pass_use_cache = self.model.config.use_cache
+ self.model.config.use_cache = False
+
+ num_batches = len(examples)
+ layers = get_module_by_name_prefix(self.model, self.layers_block_name)
+
+ cur_layer_device = get_device(layers[0])
+ data_device = cur_layer_device if cache_examples_on_gpu else CPU
+ def store_input_hook(_, args, kwargs):
+ # Positional arguments.
+ layer_input = []
+ for inp in args:
+ layer_input.append(move_to_device(inp, data_device))
+ layer_inputs.append(layer_input)
+
+ # Keyword arguments.
+ if kwargs["attention_mask"] is not None:
+ attention_masks.append(kwargs["attention_mask"].to(data_device))
+ else:
+ attention_masks.append(None)
+
+ pos_ids = kwargs.get("position_ids", None)
+ if pos_ids is not None:
+ position_ids.append(move_to_device(pos_ids, data_device))
+ one_kwargs = {}
+ for (
+ k,
+ v,
+ ) in kwargs.items(): # make sure other arguments also be captured
+ if k not in ["hidden_states", "attention_mask", "position_ids"]:
+ one_kwargs[k] = nested_move_to_device(v, data_device)
+ layer_input_kwargs.append(one_kwargs)
+ raise ValueError
+
+ force_layer_back_to_cpu = False
+ if get_device(layers[0]) == CPU:
+ layers[0] = layers[0].to(CUDA_0)
+ force_layer_back_to_cpu = True
+
+ ori_outside_layer_module_devices = {}
+ for module_name in self.outside_layer_modules:
+ module = get_module_by_name_prefix(self.model, module_name)
+
+ if module is None:
+ continue
+
+ ori_outside_layer_module_devices[module_name] = get_device(module)
+ if module is not None:
+ move_to_device(module, cur_layer_device)
+
+ # TODO: make this optional, backporting https://github.com/huggingface/optimum/blob/main/optimum/gptq/quantizer.py
+ handle = layers[0].register_forward_pre_hook(store_input_hook, with_kwargs=True)
+ for example in examples:
+ for k, v in example.items():
+ if len(v.shape) == 1:
+ v = v.unsqueeze(0)
+ example[k] = move_to_device(v, cur_layer_device)
+ try:
+ self.model(**example)
+ except ValueError:
+ pass
+ handle.remove()
+
+ move_to_device(layers[0], CPU if force_layer_back_to_cpu else cur_layer_device)
+ for module_name in self.outside_layer_modules:
+ module = get_module_by_name_prefix(self.model, module_name)
+ if module is not None:
+ move_to_device(module, ori_outside_layer_module_devices[module_name])
+
+ torch.cuda.empty_cache()
+
+ inside_layer_modules = self.inside_layer_modules
+ if not self.quantize_config.true_sequential:
+ inside_layer_modules = [sum(inside_layer_modules, [])]
+ quantizers = {}
+ for i in range(len(layers)):
+ logger.info(f"Start quantizing layer {i + 1}/{len(layers)}")
+ layer = layers[i]
+ force_layer_back_to_cpu = False
+ if get_device(layer) == CPU:
+ move_to_device(layer, CUDA_0)
+ force_layer_back_to_cpu = True
+ cur_layer_device = get_device(layer)
+
+ full = find_layers(layer)
+ for names in inside_layer_modules:
+ subset = {n: full[n] for n in names if n in full}
+ gptq = {}
+ for name in subset:
+ gptq[name] = GPTQ(subset[name])
+ gptq[name].quantizer.configure(
+ self.quantize_config.bits,
+ perchannel=True,
+ sym=self.quantize_config.sym,
+ mse=False,
+ )
+
+ def add_batch(name):
+ def tmp(_, inp, out):
+ # gptq is mutable.
+ gptq[name].add_batch(inp[0].data, out.data) # noqa: F821
+
+ return tmp
+
+ handles = []
+ for name in subset:
+ handles.append(subset[name].register_forward_hook(add_batch(name)))
+ for j in range(num_batches):
+ layer_input = []
+ for k, layer_inp in enumerate(layer_inputs[j]):
+ layer_input.append(move_to_device(layer_inp, cur_layer_device))
+
+ layer_attention_mask = move_to_device(attention_masks[j], cur_layer_device)
+ additional_layer_inputs = {"attention_mask": layer_attention_mask}
+ layer_position_ids = (
+ None if not position_ids else move_to_device(position_ids[j], cur_layer_device)
+ )
+ if layer_position_ids is not None:
+ additional_layer_inputs["position_ids"] = layer_position_ids
+ for k, v in layer_input_kwargs[j].items():
+ additional_layer_inputs[k] = nested_move_to_device(v, cur_layer_device)
+ layer(*layer_input, **additional_layer_inputs)
+ for h in handles:
+ h.remove()
+
+ for name in subset:
+ logger.info(f"Quantizing {name} in layer {i + 1}/{len(layers)}...")
+ scale, zero, g_idx = gptq[name].fasterquant(
+ percdamp=self.quantize_config.damp_percent,
+ group_size=self.quantize_config.group_size,
+ actorder=self.quantize_config.desc_act,
+ static_groups=self.quantize_config.static_groups,
+ )
+ quantizers[f"{self.layers_block_name}.{i}.{name}"] = (
+ gptq[name].quantizer.to(CPU if force_layer_back_to_cpu else cur_layer_device),
+ move_to_device(scale, CPU if force_layer_back_to_cpu else cur_layer_device),
+ move_to_device(zero, CPU if force_layer_back_to_cpu else cur_layer_device),
+ move_to_device(g_idx, CPU if force_layer_back_to_cpu else cur_layer_device),
+ )
+ gptq[name].free()
+
+ for j in range(num_batches):
+ layer_input = []
+ for k, layer_inp in enumerate(layer_inputs[j]):
+ layer_input.append(move_to_device(layer_inp, cur_layer_device))
+
+ layer_attention_mask = move_to_device(attention_masks[j], cur_layer_device)
+ additional_layer_inputs = {"attention_mask": layer_attention_mask}
+ layer_position_ids = None if not position_ids else move_to_device(position_ids[j], cur_layer_device)
+ if layer_position_ids is not None:
+ additional_layer_inputs["position_ids"] = layer_position_ids
+ for k, v in layer_input_kwargs[j].items():
+ additional_layer_inputs[k] = nested_move_to_device(v, cur_layer_device)
+ layer_output = move_to_device(
+ layer(*layer_input, **additional_layer_inputs)[0],
+ cur_layer_device if cache_examples_on_gpu else CPU,
+ )
+ layer_outputs.append([layer_output])
+
+ layers[i] = move_to_device(layer, CPU if force_layer_back_to_cpu else cur_layer_device)
+ del layer
+ del gptq
+ del layer_inputs
+ layer_inputs, layer_outputs = layer_outputs, [] # TODO: is it really OK to cache only the first positional argument?
+ torch.cuda.empty_cache()
+
+ pack_model(
+ model=self.model,
+ quantizers=quantizers,
+ bits=self.quantize_config.bits,
+ group_size=self.quantize_config.group_size,
+ use_triton=use_triton,
+ use_cuda_fp16=use_cuda_fp16,
+ desc_act=self.quantize_config.desc_act,
+ warmup_triton=autotune_warmup_after_quantized,
+ force_layer_back_to_cpu=force_layer_back_to_cpu,
+ use_marlin=self.quantize_config.checkpoint_format == CHECKPOINT_FORMAT.MARLIN,
+ )
+ if device_map:
+ self.model = remove_hook_from_module(self.model, recurse=True)
+ self.model = simple_dispatch_model(self.model, device_map)
+ self.model.config.use_cache = forward_pass_use_cache
+
+ self._quantized = True
+
+ torch.cuda.empty_cache()
+
+ @property
+ def device(self):
+ if not self.hf_device_map:
+ return self.model.device
+ else:
+ device = [d for d in self.hf_device_map.values() if d not in {"disk"}][0]
+ return torch.device(device)
+
+ def to(self, device: Union[str, torch.device]):
+ self.model.to(device)
+ return self
+
+ def forward(self, *args, **kwargs):
+ return self.model(*args, **kwargs)
+
+ def generate(self, **kwargs):
+ """shortcut for model.generate"""
+ with torch.inference_mode(), torch.amp.autocast(device_type=self.device.type):
+ return self.model.generate(**kwargs)
+
+ def prepare_inputs_for_generation(self, *args, **kwargs):
+ """shortcut for model.prepare_inputs_for_generation"""
+ return self.model.prepare_inputs_for_generation(*args, **kwargs)
+
+ def push_to_hub(
+ self,
+ repo_id: str,
+ save_dir: Optional[str] = None,
+ use_safetensors: Optional[bool] = True,
+ safetensors_metadata: Optional[Dict[str, str]] = None,
+ commit_message: Optional[str] = "Upload of AutoGPTQ quantized model",
+ use_auth_token: Optional[Union[bool, str]] = None,
+ private: Optional[bool] = None,
+ token: Optional[Union[bool, str]] = None,
+ create_pr: Optional[bool] = False,
+ ) -> str:
+ """
+ Upload the model to the Hugging Face Hub.
+
+ Parameters:
+ repo_id (`str`):
+ The name of the repository you want to push your tool to. It should contain your organization name when
+ pushing to a given organization.
+ save_dir (`str`, *optional*):
+ The name of the local folder to save the model to.
+ If the model has already been saved, this parameter can be omitted.
+ use_safetensors (`bool`, *optional*):
+ Save the model using `safetensors`.
+ If the model has already been saved, this parameter can be omitted.
+ safetensors_metadata: (`dict`, *optional*, defaults to `None`):
+ Pass optional metadata dictionary to be saved in the `safetensors` model file(s).
+ Metadata is optional and is purely for informational purposes. It does not affect inference.
+ If `None`, no metadata will be saved.
+ commit_message (`str`, *optional*, defaults to `"Upload tool"`):
+ Message to commit while pushing.
+ use_auth_token (`bool` or `str`, *optional*):
+ The token to use as HTTP bearer authorization for remote files. If `True`, will use the token generated
+ when running `huggingface-cli login` (stored in `~/.huggingface`). Will default to `True` if `repo_url`
+ is not specified.
+ private (`bool`, *optional*):
+ Whether or not the repository created should be private.
+ token (`bool` or `str`, *optional*):
+ The token to use as HTTP bearer authorization for remote files. If unset, will use the token generated
+ when running `huggingface-cli login` (stored in `~/.huggingface`).
+ create_pr (`bool`, *optional*, defaults to `False`):
+ Whether or not to create a PR with the uploaded files or directly commit.
+ """
+ if (
+ self.quantize_config.model_name_or_path is None or not isdir(self.quantize_config.model_name_or_path)
+ ) and save_dir is None:
+ raise ValueError(
+ "Quantized model should be saved first, or you can provide save_dir to make sure model is saved to local disk before uploading."
+ )
+
+ if save_dir is not None:
+ logger.info(f"Saving model to {save_dir}")
+ self.save_quantized(save_dir, use_safetensors, safetensors_metadata)
+
+ repo_url = create_repo(
+ repo_id=repo_id,
+ token=token,
+ private=private,
+ exist_ok=True,
+ repo_type="model",
+ )
+ repo_id = repo_url.repo_id
+
+ if self.quantize_config.model_name_or_path is not None:
+ work_dir = self.quantize_config.model_name_or_path
+ operations = [
+ CommitOperationAdd(path_or_fileobj=join(work_dir, f), path_in_repo=f) for f in os.listdir(work_dir)
+ ]
+ logger.info(f"Uploading the following files to {repo_id}: {','.join(os.listdir(work_dir))}")
+ return create_commit(
+ repo_id=repo_id,
+ operations=operations,
+ commit_message=commit_message,
+ token=use_auth_token,
+ create_pr=create_pr,
+ repo_type="model",
+ )
+
+ def save_quantized(
+ self,
+ save_dir: str,
+ use_safetensors: bool = True,
+ safetensors_metadata: Optional[Dict[str, str]] = None,
+ ):
+ """save quantized model and configs to local disk"""
+ os.makedirs(save_dir, exist_ok=True)
+
+ if not self.quantized:
+ raise EnvironmentError("can only save quantized model, please execute .quantize first.")
+
+ self.model.to(CPU)
+
+ model_base_name = (
+ self.quantize_config.model_file_base_name
+ or f"gptq_model-{self.quantize_config.bits}bit-{self.quantize_config.group_size}g"
+ )
+ if use_safetensors:
+ model_save_name = model_base_name + ".safetensors"
+ state_dict = self.model.state_dict()
+ state_dict = {k: v.clone().contiguous() for k, v in state_dict.items()}
+ if safetensors_metadata is None:
+ safetensors_metadata = {}
+ elif not isinstance(safetensors_metadata, dict):
+ raise TypeError("safetensors_metadata must be a dictionary.")
+ else:
+ logger.debug(f"Received safetensors_metadata: {safetensors_metadata}")
+ new_safetensors_metadata = {}
+ converted_keys = False
+ for key, value in safetensors_metadata.items():
+ if not isinstance(key, str) or not isinstance(value, str):
+ converted_keys = True
+ try:
+ new_key = str(key)
+ new_value = str(value)
+ except Exception as e:
+ raise TypeError(
+ f"safetensors_metadata: both keys and values must be strings and an error occured when trying to convert them: {e}"
+ )
+ if new_key in new_safetensors_metadata:
+ logger.warning(
+ f"After converting safetensors_metadata keys to strings, the key '{new_key}' is duplicated. Ensure that all your metadata keys are strings to avoid overwriting."
+ )
+ new_safetensors_metadata[new_key] = new_value
+ safetensors_metadata = new_safetensors_metadata
+ if converted_keys:
+ logger.debug(
+ f"One or more safetensors_metadata keys or values had to be converted to str(). Final safetensors_metadata: {safetensors_metadata}"
+ )
+
+ # Format is required to enable Accelerate to load the metadata
+ # otherwise it raises an OSError
+ safetensors_metadata["format"] = "pt"
+
+ # Store the quantization configuration as safetensors metadata
+ from auto_gptq import __version__
+
+ safetensors_metadata["auto_gptq_version"] = str(__version__)
+ safetensors_metadata["gptq_bits"] = str(self.quantize_config.bits)
+ safetensors_metadata["gptq_group_size"] = str(self.quantize_config.group_size)
+ safetensors_metadata["gptq_desc_act"] = str(self.quantize_config.desc_act)
+ safetensors_metadata["gptq_damp_percent"] = str(self.quantize_config.damp_percent)
+ safetensors_metadata["gptq_" + CHECKPOINT_FORMAT_FIELD] = self.quantize_config.checkpoint_format
+ safetensors_metadata["gptq_" + QUANT_METHOD_FIELD] = self.quantize_config.quant_method
+
+ safe_save(state_dict, join(save_dir, model_save_name), safetensors_metadata)
+ else:
+ model_save_name = model_base_name + ".bin"
+ torch.save(self.model.state_dict(), join(save_dir, model_save_name))
+
+ self.model.config.quantization_config = self.quantize_config.to_dict()
+ self.model.config.save_pretrained(save_dir)
+ self.quantize_config.save_pretrained(save_dir)
+ self.quantize_config.model_name_or_path = save_dir
+ self.quantize_config.model_file_base_name = model_base_name
+
+ def save_pretrained(
+ self,
+ save_dir: str,
+ use_safetensors: bool = True,
+ safetensors_metadata: Optional[Dict[str, str]] = None,
+ **kwargs,
+ ):
+ """alias of save_quantized"""
+ logger.warning("you are using save_pretrained, which will re-direct to save_quantized.")
+ self.save_quantized(save_dir, use_safetensors, safetensors_metadata)
+
+ @classmethod
+ def from_pretrained(
+ cls,
+ pretrained_model_name_or_path: str,
+ quantize_config: BaseQuantizeConfig,
+ max_memory: Optional[dict] = None,
+ trust_remote_code: bool = False,
+ torch_dtype: torch.dtype = torch.float16,
+ **model_init_kwargs,
+ ):
+ """load un-quantized pretrained model to cpu"""
+
+ if not torch.cuda.is_available():
+ raise EnvironmentError("Load pretrained model to do quantization requires CUDA available.")
+
+ def skip(*args, **kwargs):
+ pass
+
+ torch.nn.init.kaiming_uniform_ = skip
+ torch.nn.init.uniform_ = skip
+ torch.nn.init.normal_ = skip
+
+ # Parameters related to loading from Hugging Face Hub
+ cache_dir = model_init_kwargs.pop("cache_dir", None)
+ force_download = model_init_kwargs.pop("force_download", False)
+ resume_download = model_init_kwargs.pop("resume_download", False)
+ proxies = model_init_kwargs.pop("proxies", None)
+ local_files_only = model_init_kwargs.pop("local_files_only", False)
+ use_auth_token = model_init_kwargs.pop("use_auth_token", None)
+ revision = model_init_kwargs.pop("revision", None)
+ subfolder = model_init_kwargs.pop("subfolder", "")
+ commit_hash = model_init_kwargs.pop("_commit_hash", None)
+
+ cached_file_kwargs = {
+ "cache_dir": cache_dir,
+ "force_download": force_download,
+ "proxies": proxies,
+ "resume_download": resume_download,
+ "local_files_only": local_files_only,
+ "use_auth_token": use_auth_token,
+ "revision": revision,
+ "subfolder": subfolder,
+ "_commit_hash": commit_hash,
+ }
+
+ config = AutoConfig.from_pretrained(
+ pretrained_model_name_or_path, trust_remote_code=True, **cached_file_kwargs
+ )
+ if config.model_type not in SUPPORTED_MODELS:
+ raise TypeError(f"{config.model_type} isn't supported yet.")
+
+ # enforce some values despite user specified
+ model_init_kwargs["torch_dtype"] = torch_dtype
+ model_init_kwargs["trust_remote_code"] = trust_remote_code
+ if max_memory:
+ if "disk" in max_memory:
+ raise NotImplementedError("disk offload not support yet.")
+ with accelerate.init_empty_weights():
+ model = AutoModelForCausalLM.from_config(config, trust_remote_code=True)
+ model.tie_weights()
+
+ max_memory = accelerate.utils.get_balanced_memory(
+ model,
+ max_memory=max_memory,
+ no_split_module_classes=[cls.layer_type],
+ dtype=model_init_kwargs["torch_dtype"],
+ low_zero=False,
+ )
+ model_init_kwargs["device_map"] = accelerate.infer_auto_device_map(
+ model,
+ max_memory=max_memory,
+ no_split_module_classes=[cls.layer_type],
+ dtype=model_init_kwargs["torch_dtype"],
+ )
+ model_init_kwargs["low_cpu_mem_usage"] = True
+
+ del model
+ else:
+ model_init_kwargs["device_map"] = None
+ model_init_kwargs["low_cpu_mem_usage"] = False
+
+ torch.cuda.empty_cache()
+
+ merged_kwargs = {**model_init_kwargs, **cached_file_kwargs}
+ model = AutoModelForCausalLM.from_pretrained(pretrained_model_name_or_path, **merged_kwargs)
+
+ model_config = model.config.to_dict()
+ seq_len_keys = ["max_position_embeddings", "seq_length", "n_positions"]
+ if any(k in model_config for k in seq_len_keys):
+ for key in seq_len_keys:
+ if key in model_config:
+ model.seqlen = model_config[key]
+ break
+ else:
+ logger.warning("can't get model's sequence length from model config, will set to 4096.")
+ model.seqlen = 4096
+ model.eval()
+
+ return cls(model, False, quantize_config)
+
+ @classmethod
+ def from_quantized(
+ cls,
+ model_name_or_path: Optional[str],
+ device_map: Optional[Union[str, Dict[str, Union[int, str]]]] = None,
+ max_memory: Optional[dict] = None,
+ device: Optional[Union[str, int]] = None,
+ low_cpu_mem_usage: bool = False,
+ use_triton: bool = False,
+ use_qigen: bool = False,
+ use_marlin: bool = False,
+ torch_dtype: Optional[torch.dtype] = None,
+ inject_fused_attention: bool = False,
+ inject_fused_mlp: bool = False,
+ use_cuda_fp16: bool = True,
+ quantize_config: Optional[BaseQuantizeConfig] = None,
+ model_basename: Optional[str] = None,
+ use_safetensors: bool = True,
+ trust_remote_code: bool = False,
+ warmup_triton: bool = False,
+ trainable: bool = False,
+ disable_exllama: Optional[bool] = None,
+ disable_exllamav2: bool = False,
+ use_tritonv2: bool = False,
+ checkpoint_format: Optional[str] = None,
+ **kwargs,
+ ):
+ """load quantized model from local disk"""
+ # If disable_exllamav2 is True, we want to fall back on the exllama kernel and not the cuda/cuda_old ones.
+ if disable_exllama is None:
+ if disable_exllamav2:
+ disable_exllama = False
+ else:
+ disable_exllama = True
+
+ # Parameters related to loading from Hugging Face Hub
+ cache_dir = kwargs.pop("cache_dir", None)
+ force_download = kwargs.pop("force_download", False)
+ resume_download = kwargs.pop("resume_download", False)
+ proxies = kwargs.pop("proxies", None)
+ local_files_only = kwargs.pop("local_files_only", False)
+ use_auth_token = kwargs.pop("use_auth_token", None)
+ revision = kwargs.pop("revision", None)
+ subfolder = kwargs.pop("subfolder", "")
+ commit_hash = kwargs.pop("_commit_hash", None)
+
+ cached_file_kwargs = {
+ "cache_dir": cache_dir,
+ "force_download": force_download,
+ "proxies": proxies,
+ "resume_download": resume_download,
+ "local_files_only": local_files_only,
+ "use_auth_token": use_auth_token,
+ "revision": revision,
+ "subfolder": subfolder,
+ "_raise_exceptions_for_missing_entries": False,
+ "_commit_hash": commit_hash,
+ }
+ if use_qigen and not QIGEN_AVAILABLE:
+ logger.warning("Qigen is not installed, reset use_qigen to False.")
+ use_qigen = False
+ if use_triton and use_tritonv2:
+ logging.warn(
+ "Both use_triton and use_tritonv2 are set to True. Defaulting to use_triton"
+ )
+ use_tritonv2 = False
+ if (use_triton or use_tritonv2) and not TRITON_AVAILABLE:
+ logger.warning("Triton is not installed, reset use_triton to False.")
+ use_triton = False
+ use_tritonv2 = False
+ if not disable_exllama and not EXLLAMA_KERNELS_AVAILABLE:
+ logger.warning(
+ "Exllama kernel is not installed, reset disable_exllama to True. "
+ "This may because you installed auto_gptq using a pre-build wheel "
+ "on Windows, in which exllama_kernels are not compiled. To use "
+ "exllama_kernels to further speedup inference, you can re-install "
+ "auto_gptq from source."
+ )
+ disable_exllama = True
+ if not disable_exllamav2 and not EXLLAMAV2_KERNELS_AVAILABLE:
+ logger.warning(
+ "Exllamav2 kernel is not installed, reset disable_exllamav2 to True. "
+ "This may because you installed auto_gptq using a pre-build wheel "
+ "on Windows, in which exllama_kernels are not compiled. To use "
+ "exllama_kernels to further speedup inference, you can re-install "
+ "auto_gptq from source."
+ )
+ disable_exllamav2 = True
+ if not AUTOGPTQ_CUDA_AVAILABLE:
+ logger.warning(
+ "CUDA kernels for auto_gptq are not installed, this will result in "
+ "very slow inference speed. This may because:\n"
+ "1. You disabled CUDA extensions compilation by setting BUILD_CUDA_EXT=0 when install auto_gptq from source.\n"
+ "2. You are using pytorch without CUDA support.\n"
+ "3. CUDA and nvcc are not installed in your device."
+ )
+
+ if use_qigen and QIGEN_AVAILABLE:
+ logger.warning("QIgen is active. Ignores all settings related to cuda.")
+ inject_fused_attention = False
+ inject_fused_mlp = False
+ use_triton = False
+ disable_exllama = True
+ disable_exllamav2 = True
+
+ if not disable_exllamav2 and not disable_exllama:
+ logger.warning(
+ "You have activated both exllama and exllamav2 kernel. Setting disable_exllama to True and keeping disable_exllamav2 to False"
+ )
+ disable_exllama = True
+
+ # == step1: prepare configs and file names == #
+ config = AutoConfig.from_pretrained(
+ model_name_or_path,
+ trust_remote_code=trust_remote_code,
+ **cached_file_kwargs,
+ )
+
+ if config.model_type not in SUPPORTED_MODELS:
+ raise TypeError(f"{config.model_type} isn't supported yet.")
+
+ if quantize_config is None:
+ quantize_config = BaseQuantizeConfig.from_pretrained(model_name_or_path, checkpoint_format=checkpoint_format, **cached_file_kwargs, **kwargs)
+ else:
+ if not isinstance(quantize_config, BaseQuantizeConfig):
+ quantize_config = BaseQuantizeConfig.from_quant_config(quantize_config, checkpoint_format)
+
+ if quantize_config.checkpoint_format == CHECKPOINT_FORMAT.MARLIN:
+ # format marlin requires marlin kernel
+ use_marlin = True
+
+ marlin_compatible, marlin_optimized = _validate_marlin_device_support()
+ if use_marlin and (not MARLIN_AVAILABLE or not marlin_compatible):
+ raise TypeError("use_marlin is true but Marlin is not availble due to cuda/device support.")
+ elif use_marlin and not marlin_optimized:
+ logger.info(
+ "use_marlin is true and your gpu device is supported but not optimized for Marlin."
+ )
+
+ if not use_marlin and MARLIN_AVAILABLE:
+ unsupported_reason = _validate_marlin_compatibility(quantize_config)
+ if unsupported_reason is None and marlin_compatible:
+ logger.info(
+ "You passed a model that is compatible with the Marlin int4*fp16 GPTQ kernel but use_marlin is False. We recommend using `use_marlin=True` to use the optimized Marlin kernels for inference. Example: `model = AutoGPTQForCausalLM.from_quantized(..., use_marlin=True)`."
+ )
+
+ if model_basename is None:
+ if quantize_config.model_file_base_name:
+ possible_model_basenames = [quantize_config.model_file_base_name]
+ else:
+ possible_model_basenames = [
+ f"gptq_model-{quantize_config.bits}bit-{quantize_config.group_size}g",
+ "model",
+ ]
+ else:
+ possible_model_basenames = [model_basename]
+
+ quantize_config.model_name_or_path = model_name_or_path
+
+ extensions = []
+ if use_safetensors:
+ extensions.append(".safetensors")
+ else:
+ extensions += [".bin", ".pt"]
+
+ model_name_or_path = str(model_name_or_path)
+
+ # Retrieve (and if necessary download) the quantized checkpoint(s).
+ is_sharded, resolved_archive_file, true_model_basename = get_checkpoints(model_name_or_path=model_name_or_path, extensions=extensions, possible_model_basenames=possible_model_basenames, **cached_file_kwargs)
+
+ quantize_config.model_file_base_name = true_model_basename
+
+ model_save_name = resolved_archive_file # In case a model is sharded, this would be `model.safetensors.index.json` which may later break.
+
+ if (not disable_exllama or not disable_exllamav2) and trainable:
+ logger.warning(
+ "QuantLinear with the exllama backend not does support the trainable mode yet, switching to cuda/cuda_old/triton backend."
+ )
+ disable_exllama = True
+ disable_exllamav2 = True
+
+ elif not (use_triton or use_tritonv2) and trainable:
+ logger.warning(
+ "QuantLinear with cuda backend not support trainable mode yet, Switch to the pytorch backend."
+ )
+
+ # == step2: convert model to gptq-model (replace Linear with QuantLinear) == #
+ def skip(*args, **kwargs):
+ pass
+
+ if torch_dtype is None:
+ if not use_qigen:
+ torch_dtype = torch.float16
+ else:
+ torch_dtype = torch.float32
+
+ if torch_dtype != torch.float16:
+ logger.warning("Overriding use_cuda_fp16 to False since torch_dtype is not torch.float16.")
+ use_cuda_fp16 = False
+
+ if not use_qigen:
+ torch.nn.init.kaiming_uniform_ = skip
+ torch.nn.init.uniform_ = skip
+ torch.nn.init.normal_ = skip
+
+ transformers.modeling_utils._init_weights = False
+
+ init_contexts = [no_init_weights()]
+ if low_cpu_mem_usage:
+ init_contexts.append(accelerate.init_empty_weights(include_buffers=False))
+
+ with ContextManagers(init_contexts):
+ model = AutoModelForCausalLM.from_config(
+ config, trust_remote_code=trust_remote_code, torch_dtype=torch_dtype
+ )
+
+ layers = find_layers(model)
+ ignore_layers = [cls.lm_head_name] + cls.outside_layer_modules
+ for name in list(layers.keys()):
+ if any(name.startswith(ignore_layer) for ignore_layer in ignore_layers) or all(
+ not name.endswith(ignore_layer)
+ for sublist in cls.inside_layer_modules
+ for ignore_layer in sublist
+ ):
+ logger.info(f"The layer {name} is not quantized.")
+ del layers[name]
+
+ make_quant(
+ model,
+ layers,
+ quantize_config.bits,
+ quantize_config.group_size,
+ use_triton=use_triton,
+ disable_exllama=disable_exllama,
+ disable_exllamav2=disable_exllamav2,
+ use_cuda_fp16=use_cuda_fp16,
+ desc_act=quantize_config.desc_act,
+ trainable=trainable,
+ use_tritonv2=use_tritonv2,
+ )
+ model.tie_weights()
+
+ # == step3: load checkpoint and dispatch == #
+ if isinstance(device_map, str) and device_map not in [
+ "auto",
+ "balanced",
+ "balanced_low_0",
+ "sequential",
+ ]:
+ raise ValueError(
+ "If passing a string for `device_map`, please choose 'auto', 'balanced', 'balanced_low_0' or "
+ "'sequential'."
+ )
+ if isinstance(device_map, dict):
+ max_memory = None
+ else:
+ if device is None and not device_map and not max_memory:
+ device_map = "auto"
+ if device is not None:
+ device = torch.device(device)
+ if not max_memory and not device_map:
+ device_map = {"": device.index if device.type == "cuda" else device.type}
+ if not isinstance(device_map, dict) and device_map != "sequential":
+ max_memory = accelerate.utils.get_balanced_memory(
+ model=model,
+ max_memory=max_memory,
+ no_split_module_classes=[cls.layer_type],
+ low_zero=(device_map == "balanced_low_0"),
+ )
+ if not isinstance(device_map, dict):
+ device_map = accelerate.infer_auto_device_map(
+ model,
+ max_memory=max_memory,
+ no_split_module_classes=[cls.layer_type],
+ )
+
+ if low_cpu_mem_usage:
+ make_sure_no_tensor_in_meta_device(
+ model,
+ use_triton,
+ quantize_config.desc_act,
+ quantize_config.group_size,
+ bits=quantize_config.bits,
+ disable_exllama=disable_exllama,
+ disable_exllamav2=disable_exllamav2,
+ use_tritonv2=use_tritonv2,
+ )
+
+ # TODO: move this logic in an awq_utils.py file.
+ if quantize_config.checkpoint_format == CHECKPOINT_FORMAT.AWQ_GEMM:
+ if is_sharded:
+ raise ValueError("The loading of sharded checkpoints with AWQ checkpoints is currently not supported. Please raise an issue in AutoGPTQ repository.")
+
+ if use_marlin:
+ raise ValueError(
+ "Tried to load an AWQ model with use_marlin=True. This is currently not supported. Please open an issue in AutoGPTQ repository."
+ )
+
+ model_cache_name, is_cached = quantize_config.get_cache_file_path()
+
+ if is_cached:
+ model_save_name = model_cache_name
+ logger.info(f"Loading an AWQ model, detected a cached repacked weight at {model_save_name}.")
+ else:
+ logger.info(
+ "Loading an AWQ model. This requires repacking the weights, and no cached repacked checkpoint was found. Grab a coffee!"
+ )
+
+ if "safetensors" not in model_save_name:
+ raise NotImplementedError(
+ f"Conversion from AWQ checkpoints is implemented only for safetensors checkpoints, found {model_save_name}"
+ )
+ if quantize_config.bits != 4:
+ raise NotImplementedError(
+ f"Conversion from AWQ checkpoints is supported only for 4 bits models. Found {quantize_config.bits} bits."
+ )
+ gptq_layers = set()
+ non_gptq_params = set()
+ with safe_open(model_save_name, framework="pt") as f:
+ for state_dict_key in f.keys():
+ if (
+ "qweight" not in state_dict_key
+ and "qzeros" not in state_dict_key
+ and "scales" not in state_dict_key
+ ):
+ non_gptq_params.add(state_dict_key)
+ continue
+
+ # e.g. prefix "model.layers.3.self_attn.k_proj"
+ prefix, _ = state_dict_key.rsplit(".", 1)
+ gptq_layers.add(prefix)
+
+ new_state_dict = {}
+
+ for state_dict_key in non_gptq_params:
+ new_state_dict[state_dict_key] = f.get_tensor(state_dict_key)
+
+ gptq_layers = sorted(gptq_layers)
+ max_layer_name_length = len(max(gptq_layers, key=len))
+ pbar = tqdm(gptq_layers)
+ i = 0
+ for gptq_layer_name in pbar:
+ i += 1
+ desc = f"Unpacking {gptq_layer_name} + '...'"
+ desc = desc + " " * (max_layer_name_length - len(desc))
+
+ awq_qweight = f.get_tensor(gptq_layer_name + ".qweight")
+ awq_qzeros = f.get_tensor(gptq_layer_name + ".qzeros")
+ awq_scales = f.get_tensor(gptq_layer_name + ".scales")
+
+ # TODO: add FAST unpacking.
+ unpacked_qweight, unpacked_qzeros = unpack_awq(
+ awq_qweight,
+ awq_qzeros,
+ awq_scales,
+ bits=quantize_config.bits,
+ group_size=quantize_config.group_size,
+ )
+
+ # TODO: add FAST repacking, this is too slow.
+ desc = f"Repacking {gptq_layer_name}..."
+ desc = desc + " " * (max_layer_name_length + 12 - len(desc))
+ pbar.set_description(desc)
+ gptq_qweight, gptq_qzeros = pack_from_tensors(
+ unpacked_qweight,
+ unpacked_qzeros,
+ awq_scales,
+ bits=quantize_config.bits,
+ group_size=quantize_config.group_size,
+ )
+
+ new_state_dict[gptq_layer_name + ".qweight"] = gptq_qweight
+ new_state_dict[gptq_layer_name + ".qzeros"] = gptq_qzeros
+ new_state_dict[gptq_layer_name + ".scales"] = awq_scales
+
+ safe_save(new_state_dict, model_cache_name)
+ model_save_name = model_cache_name
+
+ if use_marlin:
+ if is_sharded:
+ raise ValueError("The loading of sharded checkpoints with Marlin is currently not supported. Please raise an issue in AutoGPTQ repository.")
+ if torch.version.hip:
+ raise ValueError("Can not use Marlin int4*fp16 kernel with AMD ROCm version of PyTorch as the kernel is not compatible. Please do not use `use_marlin=True` when using ROCm devices.")
+ if not _validate_marlin_device_support():
+ raise ValueError(f'Can not use Marlin int4*fp16 kernel with a device of compute capability {torch.cuda.get_device_capability()}, the minimum compute capability is 8.0 for Marlin kernel. Please do not use `use_marlin=True`, or please upgrade your GPU ("The more you buy, the more you save." - Taiwanese proverb).')
+
+ # Validate the model can run in Marlin.
+ if torch_dtype != torch.float16:
+ raise ValueError("Marlin kernel requires torch_dtype=torch.float16.")
+ unsupported_reason = _validate_marlin_compatibility(quantize_config)
+ if unsupported_reason is not None:
+ raise ValueError(
+ f"The model {model_name_or_path} can not be converted to use the Marlin kernel for the following reason: {unsupported_reason}, which is not supported by Marlin kernel."
+ )
+
+ # Load the quant linear type we need.
+ # TODO: load directy marlin with the right quantlinear class.
+ quant_linear_class = dynamically_import_QuantLinear(
+ use_triton=use_triton,
+ desc_act=quantize_config.desc_act,
+ group_size=quantize_config.group_size,
+ bits=quantize_config.bits,
+ disable_exllama=disable_exllama,
+ disable_exllamav2=disable_exllamav2,
+ use_marlin=False,
+ use_tritonv2=use_tritonv2, # Get the "original" QuantLienar class
+ )
+
+ # Prepare model for marlin load.
+ # If stub is marlin serialzed --> load from directly
+ # If stub has cached marlin version --> load from the cached versin
+ # Otherwise --> convert to marlin, cache, load from cache
+ model, model_save_name = prepare_model_for_marlin_load(
+ model=model,
+ quantize_config=quantize_config,
+ quant_linear_class=quant_linear_class,
+ torch_dtype=torch_dtype,
+ current_model_save_name=model_save_name,
+ device_map=device_map,
+ )
+
+ # Disable incompatible optimizations.
+ if inject_fused_attention or inject_fused_mlp:
+ # TODO: Validate whether that can be used.
+ logger.info("Disabling fused attention and mlp injection because Marlin kernel is used.")
+ inject_fused_attention = False
+ inject_fused_mlp = False
+
+ load_checkpoint_in_model(
+ model,
+ dtype=torch_dtype, # This is very hacky but works due to https://github.com/huggingface/accelerate/blob/bd72a5f1a80d5146554458823f8aeda0a9db5297/src/accelerate/utils/modeling.py#L292
+ checkpoint=model_save_name,
+ device_map=device_map,
+ offload_state_dict=True,
+ offload_buffers=True,
+ )
+
+ # TODO: Why are we using this custom function and not dispatch_model?
+ model = simple_dispatch_model(model, device_map)
+ else:
+ # Using QiGen.
+
+ if is_sharded:
+ raise ValueError("The loading of sharded checkpoints with QiGen is currently not supported. Please raise an issue in AutoGPTQ repository.")
+
+ if quantize_config.desc_act:
+ NotImplementedError("desc_act=True is not yet supported with QiGen.")
+ model = AutoModelForCausalLM.from_config(
+ config, trust_remote_code=trust_remote_code, torch_dtype=torch_dtype
+ )
+
+ layers = find_layers(model)
+ ignore_layers = [cls.lm_head_name] + cls.outside_layer_modules
+ for name in list(layers.keys()):
+ if any(name.startswith(ignore_layer) for ignore_layer in ignore_layers):
+ logger.info(f"{name} not been quantized, will be ignored when make_quant.")
+ del layers[name]
+
+ if model_save_name.endswith(".safetensors"):
+ checkpoint = safe_load(model_save_name)
+ else:
+ checkpoint = torch.load(model_save_name)
+ make_quant(
+ model,
+ layers,
+ quantize_config.bits,
+ quantize_config.group_size,
+ use_triton=use_triton,
+ disable_exllama=disable_exllama,
+ disable_exllamav2=disable_exllamav2,
+ use_cuda_fp16=use_cuda_fp16,
+ desc_act=quantize_config.desc_act,
+ trainable=trainable,
+ use_qigen=True,
+ use_tritonv2=use_tritonv2,
+ use_marlin=quantize_config.checkpoint_format == CHECKPOINT_FORMAT.MARLIN,
+ )
+ preprocess_checkpoint_qigen(
+ model,
+ layers,
+ quantize_config.bits,
+ quantize_config.group_size,
+ checkpoint,
+ )
+ model.load_state_dict(checkpoint)
+
+ # == step4: set seqlen == #
+ model_config = model.config.to_dict()
+ seq_len_keys = ["max_position_embeddings", "seq_length", "n_positions"]
+ if any(k in model_config for k in seq_len_keys):
+ for key in seq_len_keys:
+ if key in model_config:
+ model.seqlen = model_config[key]
+ break
+ else:
+ logger.warning("can't get model's sequence length from model config, will set to 4096.")
+ model.seqlen = 4096
+
+ # == step5: (optional) inject optimized module == #
+ if inject_fused_attention:
+ if cls.fused_attn_module_type is None:
+ inject_fused_attention = False
+ logger.warning(f"{cls.__name__} hasn't fused attention module yet, will skip inject fused attention.")
+ else:
+ cls.fused_attn_module_type.inject_to_model(
+ model,
+ use_triton=use_triton,
+ group_size=quantize_config.group_size,
+ use_cuda_fp16=use_cuda_fp16,
+ desc_act=quantize_config.desc_act,
+ trainable=trainable,
+ bits=quantize_config.bits,
+ disable_exllama=disable_exllama,
+ disable_exllamav2=disable_exllamav2,
+ use_tritonv2=use_tritonv2,
+ )
+ if inject_fused_mlp:
+ if cls.fused_mlp_module_type is None:
+ inject_fused_mlp = False
+ logger.warning(f"{cls.__name__} hasn't fused mlp module yet, will skip inject fused mlp.")
+ else:
+ cls.fused_mlp_module_type.inject_to_model(model, use_triton=use_triton)
+
+ # Any post-initialization that require device information, for example buffers initialization on device.
+ model = autogptq_post_init(model, use_act_order=quantize_config.desc_act)
+
+ model.eval()
+
+ # == step6: (optional) warmup triton == #
+ if (use_triton or use_tritonv2) and warmup_triton:
+ if use_tritonv2:
+ from ..nn_modules.qlinear.qlinear_tritonv2 import QuantLinear
+ else:
+ from ..nn_modules.qlinear.qlinear_triton import QuantLinear
+
+ QuantLinear.warmup(model, seqlen=model.seqlen)
+
+ if inject_fused_mlp and cls.fused_mlp_module_type is not None:
+ cls.fused_mlp_module_type.warmup(model, seqlen=model.seqlen)
+
+ # == step7: make model compatible with peft
+ # cls.make_sure_compatible_with_peft(
+ # model,
+ # use_triton,
+ # quantize_config.desc_act,
+ # quantize_config.group_size,
+ # bits=quantize_config.bits,
+ # disable_exllama=disable_exllama,
+ # disable_exllamav2=disable_exllamav2,
+ # use_marlin=use_marlin,
+ # use_qigen=use_qigen,
+ # )
+
+ return cls(
+ model,
+ True,
+ quantize_config,
+ is_triton_backend=use_triton or use_tritonv2,
+ injected_fused_attention=inject_fused_attention,
+ injected_fused_mlp=inject_fused_mlp and (use_triton or use_tritonv2),
+ trainable=trainable,
+ )
+
+ def warmup_triton(self, enabled: bool = True):
+ if not enabled:
+ return
+ if not TRITON_AVAILABLE:
+ logger.warning("triton is not available, skip warmup stage directly.")
+ return
+
+ from ..nn_modules.qlinear.qlinear_triton import QuantLinear
+
+ QuantLinear.warmup(self.model, seqlen=self.model.seqlen)
+
+ if self.fused_mlp_module_type is not None:
+ self.fused_mlp_module_type.warmup(self.model, seqlen=self.model.seqlen)
+
+ def enable_trainable_mode(self, enabled: bool = True):
+ if not self.is_triton_backend and enabled:
+ raise NotImplementedError("For now, trainable mode only supports triton backend.")
+ for n, m in self.model.named_modules():
+ if hasattr(m, "trainable"):
+ setattr(m, "trainable", enabled)
+
+ def disable_trainable_mode(self):
+ self.enable_trainable_mode(enabled=False)
+
+ @staticmethod
+ def make_sure_compatible_with_peft(
+ model: PreTrainedModel,
+ use_triton: bool,
+ desc_act: bool,
+ group_size: int,
+ bits: int,
+ disable_exllama: bool = True,
+ disable_exllamav2: bool = False,
+ use_marlin: bool = False,
+ use_qigen: bool = False,
+ use_tritonv2: bool = False,
+ ):
+ GeneralQuantLinear.inject_to_model(
+ model,
+ dynamically_import_QuantLinear(use_triton, desc_act, group_size, bits=bits, disable_exllama=disable_exllama,
+ disable_exllamav2=disable_exllamav2,
+ use_marlin=use_marlin, use_qigen=use_qigen),
+ )
+
+ def __getattr__(self, item):
+ try:
+ return super().__getattr__(item)
+ except Exception:
+ return getattr(self.model, item)
+
+
+__all__ = ["BaseGPTQForCausalLM", "BaseQuantizeConfig"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/_const.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/_const.py
new file mode 100644
index 0000000000000000000000000000000000000000..4461ce819f107c6474cc5a401849ba07e4cd512f
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/_const.py
@@ -0,0 +1,50 @@
+from torch import device
+
+from ..utils.import_utils import compare_transformers_version
+
+
+CPU = device("cpu")
+CUDA_0 = device("cuda:0")
+
+SUPPORTED_MODELS = [
+ "bloom",
+ "gptj",
+ "gpt2",
+ "gpt_neox",
+ "opt",
+ "moss",
+ "gpt_bigcode",
+ "codegen",
+ "RefinedWebModel",
+ "RefinedWeb",
+ "baichuan",
+ "internlm",
+ "qwen",
+ "xverse",
+ "deci",
+ "stablelm_epoch",
+ "mpt",
+ "cohere",
+]
+if compare_transformers_version("v4.28.0", op="ge"):
+ SUPPORTED_MODELS.append("llama")
+if compare_transformers_version("v4.30.0", op="ge"):
+ SUPPORTED_MODELS.append("longllama")
+if compare_transformers_version("v4.33.0", op="ge"):
+ SUPPORTED_MODELS.append("falcon")
+if compare_transformers_version("v4.34.0", op="ge"):
+ SUPPORTED_MODELS.append("mistral")
+ SUPPORTED_MODELS.append("Yi")
+if compare_transformers_version("v4.36.0", op="ge"):
+ SUPPORTED_MODELS.append("mixtral")
+if compare_transformers_version("v4.37.0", op="ge"):
+ SUPPORTED_MODELS.append("qwen2")
+ SUPPORTED_MODELS.append("phi")
+if compare_transformers_version("v4.38.0", op="ge"):
+ SUPPORTED_MODELS.append("gemma")
+if compare_transformers_version("v4.39.0.dev0", op="ge"):
+ SUPPORTED_MODELS.append("starcoder2")
+
+EXLLAMA_DEFAULT_MAX_INPUT_LENGTH = 2048
+
+__all__ = ["CPU", "CUDA_0", "SUPPORTED_MODELS", "EXLLAMA_DEFAULT_MAX_INPUT_LENGTH"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/_utils.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..2318dd6b9ae5c63a6d49dd64d3bce92775d72104
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/_utils.py
@@ -0,0 +1,778 @@
+import json
+import logging
+import os
+from logging import getLogger
+from typing import List, Optional, Union
+
+import accelerate
+import numpy as np
+import torch
+import torch.nn as nn
+import transformers
+from tqdm import tqdm
+from transformers import AutoConfig
+from transformers.utils.hub import cached_file
+
+from ..utils.import_utils import dynamically_import_QuantLinear
+from ..utils.modeling_utils import recurse_setattr
+from ._const import CPU, CUDA_0, EXLLAMA_DEFAULT_MAX_INPUT_LENGTH, SUPPORTED_MODELS
+
+
+logger = getLogger(__name__)
+handler = logging.StreamHandler()
+formatter = logging.Formatter("%(levelname)s - %(message)s")
+handler.setFormatter(formatter)
+logger.addHandler(handler)
+logger.setLevel(logging.INFO)
+
+
+def get_device(obj: Union[torch.Tensor, nn.Module]):
+ if isinstance(obj, torch.Tensor):
+ return obj.device
+ return next(obj.parameters()).device
+
+
+def move_to_device(obj: Optional[Union[torch.Tensor, nn.Module]], device: torch.device):
+ if obj is None:
+ return obj
+ else:
+ if get_device(obj) != device:
+ obj = obj.to(device)
+ return obj
+
+
+def find_layers(module, layers=None, name=""):
+ if not layers:
+ layers = [transformers.pytorch_utils.Conv1D, nn.Conv2d, nn.Linear]
+ for layer in layers:
+ if isinstance(module, layer):
+ return {name: module}
+ res = {}
+ for name1, child in module.named_children():
+ res.update(find_layers(child, layers=layers, name=name + "." + name1 if name != "" else name1))
+ return res
+
+
+def get_module_by_name_prefix(model, module_name: str):
+ for name, module in model.named_modules():
+ if name.startswith(module_name):
+ return module
+
+
+def get_module_by_name_suffix(model, module_name: str):
+ for name, module in model.named_modules():
+ if name.endswith(module_name):
+ return module
+
+
+def make_quant(
+ module,
+ names,
+ bits,
+ group_size,
+ name="",
+ use_triton: bool = False,
+ use_marlin: bool = False,
+ disable_exllama: Optional[bool] = None,
+ disable_exllamav2: bool = False,
+ use_qigen: bool = False,
+ use_cuda_fp16: bool = True,
+ desc_act: bool = False,
+ trainable: bool = False,
+ use_tritonv2: bool = False,
+):
+ # If disable_exllamav2 is True, we want to fall back on the exllama kernel and not the cuda/cuda_old ones.
+ if disable_exllama is None:
+ if disable_exllamav2:
+ disable_exllama = False
+ else:
+ disable_exllama = True
+
+ QuantLinear = dynamically_import_QuantLinear(
+ use_triton=use_triton,
+ desc_act=desc_act,
+ group_size=group_size,
+ bits=bits,
+ use_marlin=use_marlin,
+ disable_exllama=disable_exllama,
+ disable_exllamav2=disable_exllamav2,
+ use_qigen=use_qigen,
+ use_tritonv2=use_tritonv2,
+ )
+
+ if isinstance(module, QuantLinear):
+ return
+
+ for name, submodule in module.named_modules():
+ if name in names:
+ ori_layer_device = next(submodule.parameters()).device
+
+ if isinstance(submodule, nn.Linear):
+ in_features = submodule.in_features
+ out_features = submodule.out_features
+ elif isinstance(submodule, nn.Conv2d):
+ in_features = submodule.in_channels
+ out_features = submodule.out_channels
+ elif isinstance(submodule, transformers.pytorch_utils.Conv1D):
+ in_features = submodule.weight.shape[0]
+ out_features = submodule.weight.shape[1]
+ bias = submodule.bias is not None
+ if (
+ (not (desc_act) or group_size == -1)
+ and not use_triton
+ and not use_qigen
+ and not use_tritonv2
+ ):
+ new_layer = QuantLinear(
+ bits,
+ group_size,
+ in_features,
+ out_features,
+ bias,
+ use_cuda_fp16=use_cuda_fp16,
+ trainable=trainable,
+ weight_dtype=submodule.weight.dtype,
+ )
+ else:
+ new_layer = QuantLinear(
+ bits,
+ group_size,
+ in_features,
+ out_features,
+ bias,
+ trainable=trainable,
+ weight_dtype=submodule.weight.dtype,
+ )
+ new_layer.device = ori_layer_device
+ recurse_setattr(module, name, new_layer.to(ori_layer_device))
+
+
+def preprocess_checkpoint_qigen(
+ module,
+ names,
+ bits,
+ group_size,
+ checkpoint,
+ name="",
+):
+ try:
+ import cQIGen as qinfer
+ except ImportError:
+ logger.error("cQIGen not installed.")
+ raise
+
+ QuantLinear = dynamically_import_QuantLinear(
+ use_triton=False,
+ desc_act=False,
+ group_size=group_size,
+ bits=bits,
+ disable_exllama=False,
+ use_qigen=True,
+ )
+ if isinstance(module, QuantLinear):
+ in_features = module.infeatures
+ out_features = module.outfeatures
+
+ zeros = checkpoint[name + ".qzeros"]
+ scales = checkpoint[name + ".scales"].float()
+
+ if zeros.dtype != torch.float32:
+ new_zeros = torch.zeros_like(scales).float().contiguous()
+ if bits == 4:
+ qinfer.unpack_zeros4(zeros, new_zeros, new_zeros.shape[0], new_zeros.shape[1])
+ elif bits == 2:
+ qinfer.unpack_zeros2(zeros, new_zeros, new_zeros.shape[0], new_zeros.shape[1])
+ elif bits == 3:
+ logger.info("Unpacking zeros for 3 bits")
+ new_scales = scales.contiguous()
+ else:
+ if scales.shape[1] != out_features:
+ new_scales = scales.transpose(0, 1).contiguous()
+ else:
+ new_scales = scales.contiguous()
+ if zeros.shape[1] != out_features:
+ new_zeros = zeros.transpose(0, 1).contiguous()
+ else:
+ new_zeros = zeros.contiguous()
+
+ checkpoint[name + ".zeros"], checkpoint[name + ".scales"] = (
+ new_zeros,
+ new_scales,
+ )
+ del checkpoint[name + ".qzeros"]
+ del checkpoint[name + ".g_idx"]
+ if name + ".bias" in checkpoint:
+ checkpoint[name + ".bias"] = checkpoint[name + ".bias"].float()
+ else:
+ checkpoint[name + ".bias"] = torch.zeros(out_features)
+ checkpoint_qweight = checkpoint[name + ".qweight"].int().contiguous()
+ if bits == 4:
+ qweight = torch.zeros(int(in_features // 8 * out_features)).int().contiguous()
+ qinfer.pack4(
+ checkpoint_qweight,
+ qweight,
+ in_features // 8,
+ out_features,
+ module.mb,
+ module.tb,
+ module.cutoff,
+ ) # * (module.tt//tb))
+ elif bits == 3:
+ qweight = torch.zeros(int(in_features // 32 * 3 * out_features)).int().contiguous()
+ qinfer.pack3(
+ checkpoint_qweight,
+ qweight,
+ in_features // 32 * 3,
+ out_features,
+ module.mb // 32 * 3,
+ module.tb,
+ module.cutoff,
+ )
+ elif bits == 2:
+ qweight = torch.zeros(int(in_features // 16 * out_features)).int().contiguous()
+ qinfer.pack2(
+ checkpoint_qweight,
+ qweight,
+ in_features // 16,
+ out_features,
+ module.mb,
+ module.tb,
+ module.cutoff,
+ ) # * (module.tt//tb))
+ checkpoint[name + ".qweight"] = qweight
+ return
+
+ for name1, child in module.named_children():
+ preprocess_checkpoint_qigen(
+ child,
+ names,
+ bits,
+ group_size,
+ checkpoint,
+ name + "." + name1 if name != "" else name1,
+ )
+
+
+def pack_model(
+ model,
+ quantizers,
+ bits,
+ group_size,
+ use_triton=False,
+ use_cuda_fp16=True,
+ desc_act=False,
+ warmup_triton: bool = False,
+ force_layer_back_to_cpu: bool = False,
+ use_marlin: bool = False,
+ use_tritonv2: bool = False,
+):
+ QuantLinear = dynamically_import_QuantLinear(
+ use_triton=use_triton,
+ desc_act=desc_act,
+ group_size=group_size,
+ bits=bits,
+ disable_exllama=False,
+ disable_exllamav2=True,
+ use_marlin=use_marlin,
+ use_tritonv2=use_tritonv2,
+ )
+
+ if force_layer_back_to_cpu:
+ model.to(CPU)
+
+ logger.info("Packing model...")
+ layers = find_layers(model)
+ layers = {n: layers[n] for n in quantizers}
+ make_quant(
+ model,
+ quantizers,
+ bits,
+ group_size,
+ use_triton=use_triton,
+ use_cuda_fp16=use_cuda_fp16,
+ desc_act=desc_act,
+ disable_exllama=False,
+ disable_exllamav2=True,
+ use_marlin=use_marlin,
+ )
+ qlayers = find_layers(model, [QuantLinear])
+
+ pbar = tqdm(qlayers.keys(), leave=True)
+ for name in pbar:
+ pbar.set_description(f"Packing {name}...", refresh=True)
+
+ quantizers[name], scale, zero, g_idx = quantizers[name]
+ # so far can only pack layer on CPU
+ layer_device = qlayers[name].device
+ qlayers[name].to(CPU)
+ layers[name], scale, zero, g_idx = (
+ layers[name].to(CPU),
+ scale.to(CPU),
+ zero.to(CPU),
+ g_idx.to(CPU),
+ )
+ if QuantLinear.QUANT_TYPE == "marlin":
+ qlayers[name].pack(layers[name], scale)
+ else:
+ qlayers[name].pack(layers[name], scale, zero, g_idx)
+ qlayers[name].to(layer_device)
+ logger.info("Model packed.")
+
+ if use_triton and warmup_triton:
+ logger.warning(
+ "using autotune_warmup will move model to GPU, make sure you have enough VRAM to load the whole model."
+ )
+ QuantLinear.warmup(model.to(CUDA_0), seqlen=model.seqlen)
+
+
+def check_and_get_model_type(model_dir, trust_remote_code=False):
+ config = AutoConfig.from_pretrained(model_dir, trust_remote_code=trust_remote_code)
+ if config.model_type not in SUPPORTED_MODELS:
+ raise TypeError(f"{config.model_type} isn't supported yet.")
+ model_type = config.model_type
+ return model_type
+
+
+def simple_dispatch_model(model, device_map):
+ from accelerate.hooks import AlignDevicesHook, add_hook_to_module
+
+ if "" in device_map:
+ d = device_map[""]
+ model = model.to(torch.device(d))
+ model.hf_device_map = device_map
+ return model
+
+ tied_params = accelerate.utils.modeling.find_tied_parameters(model)
+ if set(device_map.values()) == {"cpu"} or set(device_map.values()) == {
+ "cpu",
+ "disk",
+ }:
+ main_device = "cpu"
+ else:
+ main_device = [d for d in device_map.values() if d not in ["cpu", "disk"]][0]
+
+ cpu_offload_group = [(n, d) for n, d in device_map.items() if d == "cpu"]
+ prev_hook = None
+ for idx, (n, d) in enumerate(cpu_offload_group):
+ m = get_module_by_name_suffix(model, n)
+ _, prev_hook = accelerate.cpu_offload_with_hook(m, execution_device=main_device, prev_module_hook=prev_hook)
+ # set first cpu offload module's prev_module_hook to the last cpu offload module's hook
+ if len(cpu_offload_group) > 1:
+ get_module_by_name_suffix(model, cpu_offload_group[0][0])._hf_hook.prev_module_hook = prev_hook
+
+ for n, d in device_map.items():
+ m = get_module_by_name_suffix(model, n)
+ if d != "cpu":
+ d = torch.device(d)
+ hook = AlignDevicesHook(d, io_same_device=True, place_submodules=True)
+ add_hook_to_module(m, hook)
+ accelerate.utils.modeling.retie_parameters(model, tied_params)
+ model.hf_device_map = device_map
+
+ return model
+
+
+def autogptq_post_init(model, use_act_order: bool, max_input_length: Optional[int] = None):
+ """
+ The max_input_length argument is specific to the exllama backend, that requires to initialize a buffer temp_state.
+ """
+ device_to_buffers_size = {}
+
+ model_uses_exllama = False
+ for name, submodule in model.named_modules():
+ if hasattr(submodule, "QUANT_TYPE") and submodule.QUANT_TYPE == "exllama":
+ model_uses_exllama = True
+ device = submodule.qweight.device
+ if device not in device_to_buffers_size:
+ device_to_buffers_size[device] = {
+ "max_dq_buffer_size": 1,
+ "max_inner_outer_dim": 1,
+ }
+
+ if not use_act_order:
+ submodule._use_act_order = False
+ else:
+ submodule._use_act_order = True
+
+ # Disable this heuristic for detecting act_order, but it could be used instead of the config.
+ """
+ if submodule.g_idx is None:
+ submodule.act_order = False
+ elif submodule.g_idx is not None and ((submodule.g_idx == 0).all() or torch.equal(submodule.g_idx.cpu(), torch.tensor([i // submodule.group_size for i in range(submodule.g_idx.shape[0])], dtype=torch.int32))):
+ submodule.g_idx = None
+ submodule.act_order = False
+ else:
+ submodule.act_order = True
+ """
+
+ device_to_buffers_size[device]["max_dq_buffer_size"] = max(
+ device_to_buffers_size[device]["max_dq_buffer_size"],
+ submodule.qweight.numel() * 8,
+ )
+
+ if use_act_order:
+ device_to_buffers_size[device]["max_inner_outer_dim"] = max(
+ device_to_buffers_size[device]["max_inner_outer_dim"],
+ submodule.infeatures,
+ submodule.outfeatures,
+ )
+
+ if model_uses_exllama:
+ # To be honest this is quite ugly, not proud of this.
+ try:
+ from exllama_kernels import prepare_buffers, set_tuning_params
+ except ImportError as e:
+ raise ImportError(
+ f"Could not import exllama backend dependencies prepare_buffers, set_tuning_params with the following error: {e}"
+ )
+
+ device_to_buffers = {}
+
+ if use_act_order:
+ if max_input_length is None:
+ max_input_len = EXLLAMA_DEFAULT_MAX_INPUT_LENGTH
+ else:
+ max_input_len = max_input_length
+ else:
+ if max_input_length is not None:
+ logger.info(
+ "Using exllama backend without act-order, the parameter max_input_length was set although not needed, it will be ignored."
+ )
+ max_input_len = 1
+
+ for device, buffers_size in device_to_buffers_size.items():
+ # The temp_state buffer is required to reorder X in the act-order case.
+ # The temp_dq buffer is required to dequantize weights when using cuBLAS, typically for the prefill.
+ device_to_buffers[device] = {
+ "temp_state": torch.zeros(
+ (max_input_len, buffers_size["max_inner_outer_dim"]),
+ dtype=torch.float16,
+ device=device,
+ ),
+ "temp_dq": torch.zeros(
+ (1, buffers_size["max_dq_buffer_size"]),
+ dtype=torch.float16,
+ device=device,
+ ),
+ "max_dq_buffer_size": buffers_size["max_dq_buffer_size"],
+ "max_inner_outer_dim": buffers_size["max_inner_outer_dim"],
+ }
+
+ # Buffers need to be persistent to avoid any bug.
+ model.device_to_buffers = device_to_buffers
+
+ for device, buffers in model.device_to_buffers.items():
+ prepare_buffers(device, buffers["temp_state"], buffers["temp_dq"])
+
+ # Using the default from exllama repo here.
+ matmul_recons_thd = 8
+ matmul_fused_remap = False
+ matmul_no_half2 = False
+ set_tuning_params(matmul_recons_thd, matmul_fused_remap, matmul_no_half2)
+
+ # The buffers need to have been initialized first before calling make_q4.
+ for name, submodule in model.named_modules():
+ if hasattr(submodule, "QUANT_TYPE") and submodule.QUANT_TYPE == "exllama":
+ submodule.post_init()
+
+ ## exllamav2
+ fixed_bytes = {}
+ model_uses_exllamav2 = False
+
+ for _, submodule in model.named_modules():
+ if hasattr(submodule, "QUANT_TYPE") and submodule.QUANT_TYPE == "exllamav2":
+ model_uses_exllamav2 = True
+ device = submodule.qweight.device
+ scratch_fixed = submodule.scratch_space_fixed()
+ fixed_bytes[device] = max(scratch_fixed, fixed_bytes.get(device, 0))
+
+ if model_uses_exllamav2:
+ from ..nn_modules.qlinear.qlinear_exllamav2 import ExLlamaV2DeviceTensors
+
+ device_tensors = {}
+ for device, scratch_bytes in fixed_bytes.items():
+ device_tensors[device] = ExLlamaV2DeviceTensors(device.index, scratch_bytes)
+
+ # have persistent buffers, otherwise we will get OOM
+ model.device_tensors = device_tensors
+
+ for _, submodule in model.named_modules():
+ if hasattr(submodule, "QUANT_TYPE") and submodule.QUANT_TYPE == "exllamav2":
+ device = submodule.qweight.device
+ submodule.post_init(temp_dq=model.device_tensors[device])
+ torch.cuda.empty_cache()
+
+ return model
+
+
+def make_sure_no_tensor_in_meta_device(
+ model, use_triton: bool, desc_act: bool, group_size: int, bits: int, disable_exllama: bool, disable_exllamav2: bool, use_marlin: bool = False, use_tritonv2: bool = False,
+):
+ QuantLinear = dynamically_import_QuantLinear(use_triton, desc_act, group_size, bits=bits, disable_exllama=disable_exllama, disable_exllamav2=disable_exllamav2, use_marlin=use_marlin, use_tritonv2=use_tritonv2)
+ for n, m in model.named_modules():
+ if isinstance(m, QuantLinear) and m.bias.device == torch.device("meta"):
+ m.register_buffer("bias", torch.zeros((m.outfeatures), dtype=torch.float16, device="cpu"))
+
+
+def awq_reverse_reorder_int_tensor(int_tensor, bits: int):
+ assert bits == 4
+
+ int_tensor = int_tensor.T.contiguous()
+ compress_ratio = 32 // bits
+ assert int_tensor.shape[-1] % compress_ratio == 0
+
+ order_map = [0, 2, 4, 6, 1, 3, 5, 7]
+ order_tensor = torch.tensor(order_map, dtype=torch.int32, device=int_tensor.device).reshape(1, -1)
+ order_tensor = order_tensor.repeat(int_tensor.shape[1] // compress_ratio, 1)
+ order_tensor = order_tensor + torch.arange(
+ 0,
+ int_tensor.shape[1],
+ compress_ratio,
+ dtype=torch.int32,
+ device=int_tensor.device,
+ ).reshape(-1, 1)
+ order_tensor = order_tensor.reshape(-1)
+
+ reverse_order_tensor = torch.arange(order_tensor.shape[0]).cuda()[order_tensor]
+ reverse_order_tensor = reverse_order_tensor[order_tensor]
+ int_tensor = int_tensor[:, reverse_order_tensor]
+ return int_tensor
+
+
+def unpack_awq(
+ awq_qweight: torch.Tensor,
+ awq_qzeros: torch.Tensor,
+ awq_scales: torch.Tensor,
+ bits: int,
+ group_size: int,
+):
+ """
+ Args:
+ awq_qweight (`torch.LongTensor`):
+ Expected shape: (in_features, out_features // (32 // bits))
+ awq_qzeros (`torch.LongTensor`):
+ Expected shape: (in_features // group_size, out_features // (32 // bits))
+ awq_scales (`torch.LongTensor`):
+ Expected shape: (in_features // group_size, out_features)
+
+ Returns:
+ fp16_weight (`torch.LongTensor`):
+ With shape (in_features, out_features).
+ zeros (`torch.LongTensor`):
+ With shape (in_features // group_size, out_features).
+ """
+ assert bits == 4
+
+ qzeros = awq_qzeros.cuda()
+ qweight = awq_qweight.cuda()
+ qweight = qweight.T.contiguous()
+
+ infeatures = awq_qweight.shape[0]
+
+ wf = torch.tensor(list(range(0, 32, bits)), dtype=torch.int32, device=qzeros.device).unsqueeze(0)
+ zeros = torch.bitwise_right_shift(torch.unsqueeze(qzeros, 2), wf.unsqueeze(0)).to(
+ torch.int16 if bits == 8 else torch.int8
+ )
+
+ # zeros = zeros + 1
+
+ torch.bitwise_and(zeros, (2**bits) - 1, out=zeros)
+
+ zeros = zeros.reshape(-1, 1, zeros.shape[1] * zeros.shape[2])
+
+ weight = torch.bitwise_right_shift(torch.unsqueeze(qweight, 1), wf.unsqueeze(-1)).to(
+ torch.int16 if bits == 8 else torch.int8
+ )
+ torch.bitwise_and(weight, (2**bits) - 1, out=weight)
+ weight = weight.reshape(-1, group_size, weight.shape[2])
+
+ weight = weight.view(-1, weight.shape[-1])
+ zeros = zeros.view(-1, zeros.shape[-1])
+
+ zeros = zeros.T.contiguous()
+ zeros = awq_reverse_reorder_int_tensor(zeros, bits)
+ weight = awq_reverse_reorder_int_tensor(weight, bits)
+
+ # Dequantize weights.
+ scales = awq_scales.cuda()
+ zeros = zeros.contiguous()
+ scale_zeros = zeros * scales
+
+ g_idx = torch.tensor([i // group_size for i in range(infeatures)], dtype=torch.int32)
+ scale_mat = scales[g_idx]
+ scale_zeros_mat = scale_zeros[g_idx].half()
+
+ qdq_weight_T = weight * scale_mat - scale_zeros_mat.half()
+
+ fp16_weight = qdq_weight_T.T.cuda()
+
+ return fp16_weight, zeros
+
+
+def pack_from_tensors(
+ unpacked_qweight: torch.Tensor,
+ unpacked_qzeros: torch.Tensor,
+ awq_scales: torch.Tensor,
+ bits: int,
+ group_size: int,
+):
+ """
+ Args:
+ unpacked_qweight (`torch.LongTensor`):
+ Expected shape: (in_features, out_features)
+ unpacked_qzeros (`torch.LongTensor`):
+ Expected shape: (in_features // group_size, out_features)
+ awq_scales (`torch.LongTensor`):
+ Expected shape: (in_features // group_size, out_features)
+
+ Returns:
+ qweight (`torch.LongTensor`):
+ With shape (in_features // (32 // bits), out_features)
+ qzeros (`torch.LongTensor`):
+ With shape (in_features // group_size, out_features // (32 // bits))
+ """
+ assert bits == 4
+ W = unpacked_qweight.clone().cpu()
+
+ # TODO: This should be checked somehow.
+ # if isinstance(linear, nn.Conv2d):
+ # W = W.flatten(1)
+ # if isinstance(linear, transformers.pytorch_utils.Conv1D):
+ # W = W.t()
+
+ awq_scales = awq_scales.t().contiguous()
+ unpacked_qzeros = unpacked_qzeros.contiguous()
+ unpacked_qzeros = unpacked_qzeros.cpu()
+
+ awq_scales = awq_scales.cpu()
+ scale_zeros = unpacked_qzeros.t() * awq_scales
+ scales = awq_scales.clone()
+
+ infeatures = unpacked_qweight.shape[1]
+
+ intweight = []
+ for idx in range(infeatures):
+ g_idx = idx // group_size
+
+ intweight.append(torch.round((W[:, idx] + scale_zeros[:, g_idx]) / scales[:, g_idx]).to(torch.int)[:, None])
+ intweight = torch.cat(intweight, dim=1)
+ intweight = intweight.t().contiguous()
+ intweight = intweight.numpy().astype(np.uint32)
+
+ i = 0
+ row = 0
+ qweight = np.zeros((intweight.shape[0] // 32 * bits, intweight.shape[1]), dtype=np.uint32)
+ while row < qweight.shape[0]:
+ for j in range(i, i + (32 // bits)):
+ qweight[row] |= intweight[j] << (bits * (j - i))
+ i += 32 // bits
+ row += 1
+
+ qweight = qweight.astype(np.int32)
+ qweight = torch.from_numpy(qweight)
+
+ unpacked_qzeros = unpacked_qzeros - 1
+ torch.bitwise_and(unpacked_qzeros, (2**bits) - 1, out=unpacked_qzeros)
+
+ unpacked_qzeros = unpacked_qzeros.numpy().astype(np.uint32)
+ qzeros = np.zeros(
+ (unpacked_qzeros.shape[0], unpacked_qzeros.shape[1] // 32 * bits),
+ dtype=np.uint32,
+ )
+ i = 0
+ col = 0
+ while col < qzeros.shape[1]:
+ for j in range(i, i + (32 // bits)):
+ qzeros[:, col] |= unpacked_qzeros[:, j] << (bits * (j - i))
+ i += 32 // bits
+ col += 1
+
+ qzeros = qzeros.astype(np.int32)
+ qzeros = torch.from_numpy(qzeros)
+
+ return qweight, qzeros
+
+
+def get_checkpoints(model_name_or_path: str, extensions: List[str], possible_model_basenames: List[str], **cached_file_kwargs):
+ """
+ Retrives (and if necessary downloads from Hugging Face Hub) the model checkpoint. Sharding is supported. All the `possible_model_basenames` (e.g. `["model", "model-4bit-gptq"]`) will be explored over all `extensions` (e.g. `[".bin", ".safetensors"]`).
+ """
+ searched_files = []
+ resolved_archive_file = None
+ true_model_basename = None
+
+ if os.path.isdir(model_name_or_path):
+ for ext in extensions:
+ for possible_model_basename in possible_model_basenames:
+ shard_index_name = possible_model_basename + ext + ".index.json"
+ searched_files.append(shard_index_name)
+ possible_index_file = os.path.join(model_name_or_path, shard_index_name)
+ if os.path.isfile(possible_index_file):
+ # The model is sharded over several checkpoints.
+ possible_model_basename = possible_index_file.replace(ext + ".index.json", "")
+ return True, possible_index_file, possible_model_basename
+ else:
+ model_save_name = os.path.join(model_name_or_path, possible_model_basename)
+ searched_files.append(possible_model_basename + ext)
+ if os.path.isfile(model_save_name + ext):
+ resolved_archive_file = model_save_name + ext
+ return False, resolved_archive_file, possible_model_basename
+ else:
+ temp = None
+ for ext in extensions:
+ for possible_model_basename in possible_model_basenames:
+ shard_index_name = possible_model_basename + ext + ".index.json"
+ shard_index = cached_file(
+ model_name_or_path,
+ shard_index_name,
+ **cached_file_kwargs,
+ )
+ searched_files.append(shard_index_name)
+ if shard_index is not None:
+ # The model is sharded over several checkpoints.
+ with open(str(shard_index)) as f:
+ index_json = json.load(f)
+ # Download the shards from the index.json.
+ shards = list(set(index_json["weight_map"].values()))
+ for shard in shards:
+ resolved_archive_file = cached_file(
+ model_name_or_path,
+ shard,
+ **cached_file_kwargs,
+ )
+ return True, shard_index, possible_model_basename
+ else:
+ resolved_archive_file = cached_file(
+ model_name_or_path,
+ possible_model_basename + ext,
+ **cached_file_kwargs,
+ )
+ if resolved_archive_file is None:
+ resolved_archive_file = temp
+ searched_files.append(possible_model_basename + ext)
+ if resolved_archive_file is not None:
+ temp = resolved_archive_file
+ return False, resolved_archive_file, possible_model_basename
+
+ if resolved_archive_file is None:
+ raise FileNotFoundError(
+ f"Could not find a model in {model_name_or_path} with a name in {', '.join(searched_files)}. Please specify the argument model_basename to use a custom file name."
+ )
+
+ return False, resolved_archive_file, true_model_basename
+
+
+__all__ = [
+ "get_device",
+ "move_to_device",
+ "find_layers",
+ "get_module_by_name_prefix",
+ "get_module_by_name_suffix",
+ "make_quant",
+ "preprocess_checkpoint_qigen",
+ "pack_model",
+ "autogptq_post_init",
+ "check_and_get_model_type",
+ "simple_dispatch_model",
+ "make_sure_no_tensor_in_meta_device",
+]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/auto.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/auto.py
new file mode 100644
index 0000000000000000000000000000000000000000..81b98d80b35bbd09fdb60fe447f9c5429ba70ba0
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/auto.py
@@ -0,0 +1,168 @@
+from inspect import signature
+from typing import Dict, Optional, Union
+
+from ._base import BaseGPTQForCausalLM, BaseQuantizeConfig
+from ._utils import check_and_get_model_type
+from .baichuan import BaiChuanGPTQForCausalLM
+from .bloom import BloomGPTQForCausalLM
+from .codegen import CodeGenGPTQForCausalLM
+from .cohere import CohereGPTQForCausalLM
+from .decilm import DeciLMGPTQForCausalLM
+from .gemma import GemmaGPTQForCausalLM
+from .gpt2 import GPT2GPTQForCausalLM
+from .gpt_bigcode import GPTBigCodeGPTQForCausalLM
+from .gpt_neox import GPTNeoXGPTQForCausalLM
+from .gptj import GPTJGPTQForCausalLM
+from .internlm import InternLMGPTQForCausalLM
+from .llama import LlamaGPTQForCausalLM
+from .longllama import LongLlamaGPTQForCausalLM
+from .mistral import MistralGPTQForCausalLM
+from .mixtral import MixtralGPTQForCausalLM
+from .moss import MOSSGPTQForCausalLM
+from .mpt import MPTGPTQForCausalLM
+from .opt import OPTGPTQForCausalLM
+from .phi import PhiGPTQForCausalLM
+from .qwen import QwenGPTQForCausalLM
+from .qwen2 import Qwen2GPTQForCausalLM
+from .rw import RWGPTQForCausalLM
+from .stablelmepoch import StableLMEpochGPTQForCausalLM
+from .starcoder2 import Starcoder2GPTQForCausalLM
+from .xverse import XverseGPTQForCausalLM
+from .yi import YiGPTQForCausalLM
+
+
+GPTQ_CAUSAL_LM_MODEL_MAP = {
+ "bloom": BloomGPTQForCausalLM,
+ "gpt_neox": GPTNeoXGPTQForCausalLM,
+ "gptj": GPTJGPTQForCausalLM,
+ "gpt2": GPT2GPTQForCausalLM,
+ "llama": LlamaGPTQForCausalLM,
+ "opt": OPTGPTQForCausalLM,
+ "moss": MOSSGPTQForCausalLM,
+ "gpt_bigcode": GPTBigCodeGPTQForCausalLM,
+ "codegen": CodeGenGPTQForCausalLM,
+ "cohere": CohereGPTQForCausalLM,
+ "RefinedWebModel": RWGPTQForCausalLM,
+ "RefinedWeb": RWGPTQForCausalLM,
+ "falcon": RWGPTQForCausalLM,
+ "baichuan": BaiChuanGPTQForCausalLM,
+ "internlm": InternLMGPTQForCausalLM,
+ "qwen": QwenGPTQForCausalLM,
+ "mistral": MistralGPTQForCausalLM,
+ "Yi": YiGPTQForCausalLM,
+ "xverse": XverseGPTQForCausalLM,
+ "deci": DeciLMGPTQForCausalLM,
+ "stablelm_epoch": StableLMEpochGPTQForCausalLM,
+ "starcoder2": Starcoder2GPTQForCausalLM,
+ "mixtral": MixtralGPTQForCausalLM,
+ "qwen2": Qwen2GPTQForCausalLM,
+ "longllama": LongLlamaGPTQForCausalLM,
+ "gemma": GemmaGPTQForCausalLM,
+ "phi": PhiGPTQForCausalLM,
+ "mpt": MPTGPTQForCausalLM,
+}
+
+
+class AutoGPTQForCausalLM:
+ def __init__(self):
+ raise EnvironmentError(
+ "AutoGPTQModelForCausalLM is designed to be instantiated\n"
+ "using `AutoGPTQModelForCausalLM.from_pretrained` if want to quantize a pretrained model.\n"
+ "using `AutoGPTQModelForCausalLM.from_quantized` if want to inference with quantized model."
+ )
+
+ @classmethod
+ def from_pretrained(
+ cls,
+ pretrained_model_name_or_path: str,
+ quantize_config: BaseQuantizeConfig,
+ max_memory: Optional[dict] = None,
+ trust_remote_code: bool = False,
+ **model_init_kwargs,
+ ) -> BaseGPTQForCausalLM:
+ model_type = check_and_get_model_type(pretrained_model_name_or_path, trust_remote_code)
+ return GPTQ_CAUSAL_LM_MODEL_MAP[model_type].from_pretrained(
+ pretrained_model_name_or_path=pretrained_model_name_or_path,
+ quantize_config=quantize_config,
+ max_memory=max_memory,
+ trust_remote_code=trust_remote_code,
+ **model_init_kwargs,
+ )
+
+ @classmethod
+ def from_quantized(
+ cls,
+ model_name_or_path: Optional[str],
+ device_map: Optional[Union[str, Dict[str, Union[str, int]]]] = None,
+ max_memory: Optional[dict] = None,
+ device: Optional[Union[str, int]] = None,
+ low_cpu_mem_usage: bool = False,
+ use_triton: bool = False,
+ inject_fused_attention: bool = False,
+ inject_fused_mlp: bool = False,
+ use_cuda_fp16: bool = True,
+ quantize_config: Optional[BaseQuantizeConfig] = None,
+ model_basename: Optional[str] = None,
+ use_safetensors: bool = True,
+ trust_remote_code: bool = False,
+ warmup_triton: bool = False,
+ trainable: bool = False,
+ disable_exllama: Optional[bool] = None,
+ disable_exllamav2: bool = False,
+ use_marlin: bool = False,
+ use_tritonv2: bool = False,
+ **kwargs,
+ ) -> BaseGPTQForCausalLM:
+ # If disable_exllamav2 is True, we want to fall back on the exllama kernel and not the cuda/cuda_old ones.
+ if disable_exllama is None:
+ if disable_exllamav2:
+ disable_exllama = False
+ else:
+ disable_exllama = True
+
+ model_type = check_and_get_model_type(model_name_or_path, trust_remote_code)
+ quant_func = GPTQ_CAUSAL_LM_MODEL_MAP[model_type].from_quantized
+ # A static list of kwargs needed for huggingface_hub
+ huggingface_kwargs = [
+ "cache_dir",
+ "force_download",
+ "proxies",
+ "resume_download",
+ "local_files_only",
+ "use_auth_token",
+ "revision",
+ "subfolder",
+ "_raise_exceptions_for_missing_entries",
+ "_commit_hash",
+ ]
+ # TODO: do we need this filtering of kwargs? @PanQiWei is there a reason we can't just pass all kwargs?
+ keywords = {
+ key: kwargs[key]
+ for key in list(signature(quant_func).parameters.keys()) + huggingface_kwargs
+ if key in kwargs
+ }
+ return quant_func(
+ model_name_or_path=model_name_or_path,
+ device_map=device_map,
+ max_memory=max_memory,
+ device=device,
+ low_cpu_mem_usage=low_cpu_mem_usage,
+ use_triton=use_triton,
+ inject_fused_attention=inject_fused_attention,
+ inject_fused_mlp=inject_fused_mlp,
+ use_cuda_fp16=use_cuda_fp16,
+ quantize_config=quantize_config,
+ model_basename=model_basename,
+ use_safetensors=use_safetensors,
+ trust_remote_code=trust_remote_code,
+ warmup_triton=warmup_triton,
+ trainable=trainable,
+ disable_exllama=disable_exllama,
+ disable_exllamav2=disable_exllamav2,
+ use_marlin=use_marlin,
+ use_tritonv2=use_tritonv2,
+ **keywords,
+ )
+
+
+__all__ = ["AutoGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/baichuan.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/baichuan.py
new file mode 100644
index 0000000000000000000000000000000000000000..96b83024194be5b9d2be963a278a736680d49dc4
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/baichuan.py
@@ -0,0 +1,16 @@
+from ._base import BaseGPTQForCausalLM
+
+
+class BaiChuanGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "DecoderLayer"
+ layers_block_name = "model.layers"
+ outside_layer_modules = ["model.embed_tokens", "model.norm"]
+ inside_layer_modules = [
+ ["self_attn.W_pack"],
+ ["self_attn.o_proj"],
+ ["mlp.up_proj", "mlp.gate_proj"],
+ ["mlp.down_proj"],
+ ]
+
+
+__all__ = ["BaiChuanGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/bloom.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/bloom.py
new file mode 100644
index 0000000000000000000000000000000000000000..f7471a9685c26fc26a1c6845fb0d714546a22e73
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/bloom.py
@@ -0,0 +1,20 @@
+from ._base import BaseGPTQForCausalLM
+
+
+class BloomGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "BloomBlock"
+ layers_block_name = "transformer.h"
+ outside_layer_modules = [
+ "transformer.word_embeddings",
+ "transformer.word_embeddings_layernorm",
+ "transformer.ln_f",
+ ]
+ inside_layer_modules = [
+ ["self_attention.query_key_value"],
+ ["self_attention.dense"],
+ ["mlp.dense_h_to_4h"],
+ ["mlp.dense_4h_to_h"],
+ ]
+
+
+__all__ = ["BloomGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/codegen.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/codegen.py
new file mode 100644
index 0000000000000000000000000000000000000000..2e656ab932d9e6708f26d6a4a8d05b0ad39541a4
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/codegen.py
@@ -0,0 +1,16 @@
+from ._base import BaseGPTQForCausalLM
+
+
+class CodeGenGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "CodeGenBlock"
+ layers_block_name = "transformer.h"
+ outside_layer_modules = ["transformer.wte", "transformer.ln_f"]
+ inside_layer_modules = [
+ ["attn.qkv_proj"],
+ ["attn.out_proj"],
+ ["mlp.fc_in"],
+ ["mlp.fc_out"],
+ ]
+
+
+__all__ = ["CodeGenGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/cohere.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/cohere.py
new file mode 100644
index 0000000000000000000000000000000000000000..5271d8d3c24e60a5e14b7851793f0f98b3687889
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/cohere.py
@@ -0,0 +1,20 @@
+from logging import getLogger
+
+from ._base import BaseGPTQForCausalLM
+
+
+logger = getLogger(__name__)
+
+class CohereGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "CohereDecoderLayer"
+ layers_block_name = "model.layers"
+ outside_layer_modules = ["model.embed_tokens", "model.norm"]
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.o_proj"],
+ ["mlp.up_proj", "mlp.gate_proj"],
+ ["mlp.down_proj"],
+ ]
+
+__all__ = ["CohereGPTQForCausalLM"]
+
\ No newline at end of file
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/decilm.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/decilm.py
new file mode 100644
index 0000000000000000000000000000000000000000..67f2dc91511b2672cbc7653c72cc6b8211681051
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/decilm.py
@@ -0,0 +1,32 @@
+from logging import getLogger
+
+from ..utils.import_utils import compare_transformers_version
+from ._base import BaseGPTQForCausalLM
+
+
+if compare_transformers_version("v4.28.0", op="ge"):
+ from ..nn_modules.fused_llama_attn import FusedLlamaAttentionForQuantizedModel
+ from ..nn_modules.fused_llama_mlp import FusedLlamaMLPForQuantizedModel
+else:
+ FusedLlamaAttentionForQuantizedModel = None
+ FusedLlamaMLPForQuantizedModel = None
+
+logger = getLogger(__name__)
+
+
+class DeciLMGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "DeciLMDecoderLayer"
+ layers_block_name = "model.layers"
+ outside_layer_modules = ["model.embed_tokens", "model.norm"]
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.o_proj"],
+ ["mlp.up_proj", "mlp.gate_proj"],
+ ["mlp.down_proj"],
+ ]
+
+ fused_attn_module_type = FusedLlamaAttentionForQuantizedModel
+ fused_mlp_module_type = FusedLlamaMLPForQuantizedModel
+
+
+__all__ = ["DeciLMGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/gemma.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/gemma.py
new file mode 100644
index 0000000000000000000000000000000000000000..581732cff6561d31fdf4b5b7abfc1a8c2ec7653f
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/gemma.py
@@ -0,0 +1,21 @@
+from logging import getLogger
+
+from ._base import BaseGPTQForCausalLM
+
+
+logger = getLogger(__name__)
+
+
+class GemmaGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "GemmaDecoderLayer"
+ layers_block_name = "model.layers"
+ outside_layer_modules = ["model.embed_tokens", "model.norm"]
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.o_proj"],
+ ["mlp.up_proj", "mlp.gate_proj"],
+ ["mlp.down_proj"],
+ ]
+
+
+__all__ = ["GemmaGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/gpt2.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/gpt2.py
new file mode 100644
index 0000000000000000000000000000000000000000..f8654a74e6c2ee3d29c994ecbfef7fc8e3cf2bac
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/gpt2.py
@@ -0,0 +1,16 @@
+from ._base import BaseGPTQForCausalLM
+
+
+class GPT2GPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "GPT2Block"
+ layers_block_name = "transformer.h"
+ outside_layer_modules = ["transformer.wte", "transformer.wpe", "transformer.ln_f"]
+ inside_layer_modules = [
+ ["attn.c_attn"],
+ ["attn.c_proj"],
+ ["mlp.c_fc"],
+ ["mlp.c_proj"],
+ ]
+
+
+__all__ = ["GPT2GPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/gpt_bigcode.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/gpt_bigcode.py
new file mode 100644
index 0000000000000000000000000000000000000000..5943b0f1db14c4b9e3347ca7029fdc2e4424915c
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/gpt_bigcode.py
@@ -0,0 +1,16 @@
+from ._base import BaseGPTQForCausalLM
+
+
+class GPTBigCodeGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "GPTBigCodeBlock"
+ layers_block_name = "transformer.h"
+ outside_layer_modules = ["transformer.wpe", "transformer.wte", "transformer.ln_f"]
+ inside_layer_modules = [
+ ["attn.c_attn"],
+ ["attn.c_proj"],
+ ["mlp.c_fc"],
+ ["mlp.c_proj"],
+ ]
+
+
+__all__ = ["GPTBigCodeGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/gpt_neox.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/gpt_neox.py
new file mode 100644
index 0000000000000000000000000000000000000000..52f4a0b73816f6b8d811cfda7ab49464629bc568
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/gpt_neox.py
@@ -0,0 +1,17 @@
+from ._base import BaseGPTQForCausalLM
+
+
+class GPTNeoXGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "GPTNeoXLayer"
+ layers_block_name = "gpt_neox.layers"
+ outside_layer_modules = ["gpt_neox.embed_in", "gpt_neox.final_layer_norm"]
+ inside_layer_modules = [
+ ["attention.query_key_value"],
+ ["attention.dense"],
+ ["mlp.dense_h_to_4h"],
+ ["mlp.dense_4h_to_h"],
+ ]
+ lm_head_name = "embed_out"
+
+
+__all__ = ["GPTNeoXGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/gptj.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/gptj.py
new file mode 100644
index 0000000000000000000000000000000000000000..5309f081b9472fc2b388f003b75d016db2b4425c
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/gptj.py
@@ -0,0 +1,19 @@
+from ..nn_modules.fused_gptj_attn import FusedGPTJAttentionForQuantizedModel
+from ._base import BaseGPTQForCausalLM
+
+
+class GPTJGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "GPTJBlock"
+ layers_block_name = "transformer.h"
+ outside_layer_modules = ["transformer.wte", "transformer.ln_f"]
+ inside_layer_modules = [
+ ["attn.k_proj", "attn.v_proj", "attn.q_proj"],
+ ["attn.out_proj"],
+ ["mlp.fc_in"],
+ ["mlp.fc_out"],
+ ]
+
+ fused_attn_module_type = FusedGPTJAttentionForQuantizedModel
+
+
+__all__ = ["GPTJGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/internlm.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/internlm.py
new file mode 100644
index 0000000000000000000000000000000000000000..40c55e1a81e29e1c23d27ef0f1271e50c7aada19
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/internlm.py
@@ -0,0 +1,16 @@
+from ._base import BaseGPTQForCausalLM
+
+
+class InternLMGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "InternLMDecoderLayer"
+ layers_block_name = "model.layers"
+ outside_layer_modules = ["model.embed_tokens", "model.norm"]
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.o_proj"],
+ ["mlp.up_proj", "mlp.gate_proj"],
+ ["mlp.down_proj"],
+ ]
+
+
+__all__ = ["InternLMGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/llama.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/llama.py
new file mode 100644
index 0000000000000000000000000000000000000000..0841551f1c1bedd71e025e8a0fc4ceaf7c0264e5
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/llama.py
@@ -0,0 +1,32 @@
+from logging import getLogger
+
+from ..utils.import_utils import compare_transformers_version
+from ._base import BaseGPTQForCausalLM
+
+
+if compare_transformers_version("v4.28.0", op="ge"):
+ from ..nn_modules.fused_llama_attn import FusedLlamaAttentionForQuantizedModel
+ from ..nn_modules.fused_llama_mlp import FusedLlamaMLPForQuantizedModel
+else:
+ FusedLlamaAttentionForQuantizedModel = None
+ FusedLlamaMLPForQuantizedModel = None
+
+logger = getLogger(__name__)
+
+
+class LlamaGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "LlamaDecoderLayer"
+ layers_block_name = "model.layers"
+ outside_layer_modules = ["model.embed_tokens", "model.norm"]
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.o_proj"],
+ ["mlp.up_proj", "mlp.gate_proj"],
+ ["mlp.down_proj"],
+ ]
+
+ fused_attn_module_type = FusedLlamaAttentionForQuantizedModel
+ fused_mlp_module_type = FusedLlamaMLPForQuantizedModel
+
+
+__all__ = ["LlamaGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/longllama.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/longllama.py
new file mode 100644
index 0000000000000000000000000000000000000000..8cc737d3006dcb35a6d7c4e498a26cd365c0e370
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/longllama.py
@@ -0,0 +1,32 @@
+from logging import getLogger
+
+from ..utils.import_utils import compare_transformers_version
+from ._base import BaseGPTQForCausalLM
+
+
+if compare_transformers_version("v4.28.0", op="ge"):
+ from ..nn_modules.fused_llama_attn import FusedLlamaAttentionForQuantizedModel
+ from ..nn_modules.fused_llama_mlp import FusedLlamaMLPForQuantizedModel
+else:
+ FusedLlamaAttentionForQuantizedModel = None
+ FusedLlamaMLPForQuantizedModel = None
+
+logger = getLogger(__name__)
+
+
+class LongLlamaGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "LongLlamaDecoderLayer"
+ layers_block_name = "model.layers"
+ outside_layer_modules = ["model.embed_tokens", "model.norm"]
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.o_proj"],
+ ["mlp.up_proj", "mlp.gate_proj"],
+ ["mlp.down_proj"],
+ ]
+
+ fused_attn_module_type = FusedLlamaAttentionForQuantizedModel
+ fused_mlp_module_type = FusedLlamaMLPForQuantizedModel
+
+
+__all__ = ["LongLlamaGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/mistral.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/mistral.py
new file mode 100644
index 0000000000000000000000000000000000000000..847a78bfccfa54c6d9d54f816af590b44c3c6e27
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/mistral.py
@@ -0,0 +1,16 @@
+from ._base import BaseGPTQForCausalLM
+
+
+class MistralGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "MistralDecoderLayer"
+ layers_block_name = "model.layers"
+ outside_layer_modules = ["model.embed_tokens", "model.norm"]
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.o_proj"],
+ ["mlp.up_proj", "mlp.gate_proj"],
+ ["mlp.down_proj"],
+ ]
+
+
+__all__ = ["MistralGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/mixtral.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/mixtral.py
new file mode 100644
index 0000000000000000000000000000000000000000..74c621e65dadf29f87542e70e7a3565065ca34f4
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/mixtral.py
@@ -0,0 +1,42 @@
+from ._base import BaseGPTQForCausalLM
+
+
+class MixtralGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "MixtralDecoderLayer"
+ layers_block_name = "model.layers"
+ outside_layer_modules = ["model.embed_tokens", "model.norm"]
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.o_proj"],
+ [
+ "block_sparse_moe.experts.0.w1",
+ "block_sparse_moe.experts.1.w1",
+ "block_sparse_moe.experts.2.w1",
+ "block_sparse_moe.experts.3.w1",
+ "block_sparse_moe.experts.4.w1",
+ "block_sparse_moe.experts.5.w1",
+ "block_sparse_moe.experts.6.w1",
+ "block_sparse_moe.experts.7.w1",
+ "block_sparse_moe.experts.0.w3",
+ "block_sparse_moe.experts.1.w3",
+ "block_sparse_moe.experts.2.w3",
+ "block_sparse_moe.experts.3.w3",
+ "block_sparse_moe.experts.4.w3",
+ "block_sparse_moe.experts.5.w3",
+ "block_sparse_moe.experts.6.w3",
+ "block_sparse_moe.experts.7.w3",
+ ],
+ [
+ "block_sparse_moe.experts.0.w2",
+ "block_sparse_moe.experts.1.w2",
+ "block_sparse_moe.experts.2.w2",
+ "block_sparse_moe.experts.3.w2",
+ "block_sparse_moe.experts.4.w2",
+ "block_sparse_moe.experts.5.w2",
+ "block_sparse_moe.experts.6.w2",
+ "block_sparse_moe.experts.7.w2",
+ ],
+ ]
+
+
+__all__ = ["MixtralGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/moss.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/moss.py
new file mode 100644
index 0000000000000000000000000000000000000000..6ed30fb619736123a1f779e58c8ef8a5f604c2d2
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/moss.py
@@ -0,0 +1,16 @@
+from ._base import BaseGPTQForCausalLM
+
+
+class MOSSGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "MossBlock"
+ layers_block_name = "transformer.h"
+ outside_layer_modules = ["transformer.wte", "transformer.ln_f"]
+ inside_layer_modules = [
+ ["attn.qkv_proj"],
+ ["attn.out_proj"],
+ ["mlp.fc_in"],
+ ["mlp.fc_out"],
+ ]
+
+
+__all__ = ["MOSSGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/mpt.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/mpt.py
new file mode 100644
index 0000000000000000000000000000000000000000..5da1eb654b9f363d28a6cba8cda2cf4f5bd9960c
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/mpt.py
@@ -0,0 +1,19 @@
+from auto_gptq.modeling import BaseGPTQForCausalLM
+
+
+class MPTGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "MPTBlock"
+ layers_block_name = "transformer.blocks"
+ outside_layer_modules = [
+ "transformer.wte", "transformer.norm_f"
+ ]
+
+ inside_layer_modules = [
+ ["attn.Wqkv"],
+ ["attn.out_proj"],
+ ["ffn.up_proj"],
+ ["ffn.down_proj"]
+ ]
+
+
+__all__ = ["MPTGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/opt.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/opt.py
new file mode 100644
index 0000000000000000000000000000000000000000..6279569644e0b66987c77c9aa2d8a1bf6118c3be
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/opt.py
@@ -0,0 +1,22 @@
+from ._base import BaseGPTQForCausalLM
+
+
+class OPTGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "OPTDecoderLayer"
+ layers_block_name = "model.decoder.layers"
+ outside_layer_modules = [
+ "model.decoder.embed_tokens",
+ "model.decoder.embed_positions",
+ "model.decoder.project_out",
+ "model.decoder.project_in",
+ "model.decoder.final_layer_norm",
+ ]
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.out_proj"],
+ ["fc1"],
+ ["fc2"],
+ ]
+
+
+__all__ = ["OPTGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/phi.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/phi.py
new file mode 100644
index 0000000000000000000000000000000000000000..240d32d90f2679e9ab3126e3d22d89263cb9f911
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/phi.py
@@ -0,0 +1,18 @@
+from ._base import BaseGPTQForCausalLM
+
+
+class PhiGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "PhiDecoderLayer"
+ layers_block_name = "model.layers"
+ outside_layer_modules = ["model.embed_tokens", "model.final_layernorm"]
+ inside_layer_modules = [
+ ["self_attn.q_proj"],
+ ["self_attn.k_proj"],
+ ["self_attn.v_proj"],
+ ["self_attn.dense"],
+ ["mlp.fc1"],
+ ["mlp.fc2"],
+ ]
+
+
+__all__ = ["PhiGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/qwen.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/qwen.py
new file mode 100644
index 0000000000000000000000000000000000000000..4354db6e5e2036c1c87b5c4541f010db622b34ea
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/qwen.py
@@ -0,0 +1,21 @@
+from ._base import BaseGPTQForCausalLM
+
+
+class QwenGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "QWenBlock"
+ layers_block_name = "transformer.h"
+ outside_layer_modules = [
+ "transformer.wte",
+ "transformer.wpe",
+ "transformer.ln_f",
+ "transformer.visual",
+ ]
+ inside_layer_modules = [
+ ["attn.c_attn"],
+ ["attn.c_proj"],
+ ["mlp.w1", "mlp.w2"],
+ ["mlp.c_proj"],
+ ]
+
+
+__all__ = ["QwenGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/qwen2.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/qwen2.py
new file mode 100644
index 0000000000000000000000000000000000000000..03755676a04761c49c7ec3f6702ccf5f7636c9c7
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/qwen2.py
@@ -0,0 +1,16 @@
+from ._base import BaseGPTQForCausalLM
+
+
+class Qwen2GPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "Qwen2DecoderLayer"
+ layers_block_name = "model.layers"
+ outside_layer_modules = ["model.embed_tokens", "model.norm"]
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.o_proj"],
+ ["mlp.up_proj", "mlp.gate_proj"],
+ ["mlp.down_proj"],
+ ]
+
+
+__all__ = ["Qwen2GPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/rw.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/rw.py
new file mode 100644
index 0000000000000000000000000000000000000000..5d95fc65df3308c4324a4f7ae86f40f7d792e86b
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/rw.py
@@ -0,0 +1,16 @@
+from ._base import BaseGPTQForCausalLM
+
+
+class RWGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "DecoderLayer"
+ layers_block_name = "transformer.h"
+ outside_layer_modules = ["transformer.word_embeddings", "transformer.ln_f"]
+ inside_layer_modules = [
+ ["self_attention.query_key_value"],
+ ["self_attention.dense"],
+ ["mlp.dense_h_to_4h"],
+ ["mlp.dense_4h_to_h"],
+ ]
+
+
+__all__ = ["RWGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/stablelmepoch.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/stablelmepoch.py
new file mode 100644
index 0000000000000000000000000000000000000000..9d2b404396775727d78b9160989b18ec21db8642
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/stablelmepoch.py
@@ -0,0 +1,32 @@
+from logging import getLogger
+
+from ..utils.import_utils import compare_transformers_version
+from ._base import BaseGPTQForCausalLM
+
+
+if compare_transformers_version("v4.28.0", op="ge"):
+ from ..nn_modules.fused_llama_attn import FusedLlamaAttentionForQuantizedModel
+ from ..nn_modules.fused_llama_mlp import FusedLlamaMLPForQuantizedModel
+else:
+ FusedLlamaAttentionForQuantizedModel = None
+ FusedLlamaMLPForQuantizedModel = None
+
+logger = getLogger(__name__)
+
+
+class StableLMEpochGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "DecoderLayer"
+ layers_block_name = "model.layers"
+ outside_layer_modules = ["model.embed_tokens", "model.norm"]
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.o_proj"],
+ ["mlp.up_proj", "mlp.gate_proj"],
+ ["mlp.down_proj"],
+ ]
+
+ fused_attn_module_type = FusedLlamaAttentionForQuantizedModel
+ fused_mlp_module_type = FusedLlamaMLPForQuantizedModel
+
+
+__all__ = ["StableLMEpochGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/starcoder2.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/starcoder2.py
new file mode 100644
index 0000000000000000000000000000000000000000..cb77ac1a6349e84e29066b1bd823c051f8a87f11
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/starcoder2.py
@@ -0,0 +1,21 @@
+from logging import getLogger
+
+from ._base import BaseGPTQForCausalLM
+
+
+logger = getLogger(__name__)
+
+
+class Starcoder2GPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "Starcoder2DecoderLayer"
+ layers_block_name = "model.layers"
+ outside_layer_modules = ["model.embed_tokens", "model.norm"]
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.o_proj"],
+ ["mlp.c_fc"],
+ ["mlp.c_proj"],
+ ]
+
+
+__all__ = ["Starcoder2GPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/xverse.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/xverse.py
new file mode 100644
index 0000000000000000000000000000000000000000..63db8d436181c6a7f83a0369b617f62bff38ca13
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/xverse.py
@@ -0,0 +1,32 @@
+from logging import getLogger
+
+from ..utils.import_utils import compare_transformers_version
+from ._base import BaseGPTQForCausalLM
+
+
+if compare_transformers_version("v4.28.0", op="ge"):
+ from ..nn_modules.fused_llama_attn import FusedLlamaAttentionForQuantizedModel
+ from ..nn_modules.fused_llama_mlp import FusedLlamaMLPForQuantizedModel
+else:
+ FusedLlamaAttentionForQuantizedModel = None
+ FusedLlamaMLPForQuantizedModel = None
+
+logger = getLogger(__name__)
+
+
+class XverseGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "XverseDecoderLayer"
+ layers_block_name = "model.layers"
+ outside_layer_modules = ["model.embed_tokens", "model.norm"]
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.o_proj"],
+ ["mlp.up_proj", "mlp.gate_proj"],
+ ["mlp.down_proj"],
+ ]
+
+ fused_attn_module_type = FusedLlamaAttentionForQuantizedModel
+ fused_mlp_module_type = FusedLlamaMLPForQuantizedModel
+
+
+__all__ = ["XverseGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/yi.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/yi.py
new file mode 100644
index 0000000000000000000000000000000000000000..0bb97c98a1a0dcc3af7201beb3aad0a78c68d029
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/modeling/yi.py
@@ -0,0 +1,32 @@
+from logging import getLogger
+
+from ..utils.import_utils import compare_transformers_version
+from ._base import BaseGPTQForCausalLM
+
+
+if compare_transformers_version("v4.28.0", op="ge"):
+ from ..nn_modules.fused_llama_attn import FusedLlamaAttentionForQuantizedModel
+ from ..nn_modules.fused_llama_mlp import FusedLlamaMLPForQuantizedModel
+else:
+ FusedLlamaAttentionForQuantizedModel = None
+ FusedLlamaMLPForQuantizedModel = None
+
+logger = getLogger(__name__)
+
+
+class YiGPTQForCausalLM(BaseGPTQForCausalLM):
+ layer_type = "YiDecoderLayer"
+ layers_block_name = "model.layers"
+ outside_layer_modules = ["model.embed_tokens", "model.norm"]
+ inside_layer_modules = [
+ ["self_attn.k_proj", "self_attn.v_proj", "self_attn.q_proj"],
+ ["self_attn.o_proj"],
+ ["mlp.up_proj", "mlp.gate_proj"],
+ ["mlp.down_proj"],
+ ]
+
+ fused_attn_module_type = FusedLlamaAttentionForQuantizedModel
+ fused_mlp_module_type = FusedLlamaMLPForQuantizedModel
+
+
+__all__ = ["YiGPTQForCausalLM"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/__init__.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/_fused_base.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/_fused_base.py
new file mode 100644
index 0000000000000000000000000000000000000000..7d899625cc8a36e2828b71bf54cb9d42fc155a00
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/_fused_base.py
@@ -0,0 +1,36 @@
+from abc import abstractmethod
+from logging import getLogger
+
+import torch.nn as nn
+
+from .triton_utils.mixin import TritonModuleMixin
+
+
+logger = getLogger(__name__)
+
+
+class FusedBaseModule(nn.Module, TritonModuleMixin):
+ @classmethod
+ @abstractmethod
+ def inject_to_model(cls, *args, **kwargs):
+ raise NotImplementedError()
+
+
+class FusedBaseAttentionModule(FusedBaseModule):
+ @classmethod
+ @abstractmethod
+ def inject_to_model(
+ cls, model, use_triton=False, group_size=-1, use_cuda_fp16=True, desc_act=False, trainable=False, **kwargs
+ ):
+ raise NotImplementedError()
+
+ @classmethod
+ def warmup(cls, model, transpose=False, seqlen=2048):
+ pass
+
+
+class FusedBaseMLPModule(FusedBaseModule):
+ @classmethod
+ @abstractmethod
+ def inject_to_model(cls, model, use_triton=False, **kwargs):
+ raise NotImplementedError()
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/fused_gptj_attn.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/fused_gptj_attn.py
new file mode 100644
index 0000000000000000000000000000000000000000..85f6c349f84febfd09dec492bee8e3781978bfe1
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/fused_gptj_attn.py
@@ -0,0 +1,314 @@
+from typing import Optional, Tuple, Union
+
+import torch
+import torch.nn as nn
+from torch.nn import functional as F
+from transformers.models.gptj.modeling_gptj import GPTJAttention
+
+from ..utils.import_utils import compare_pytorch_version, dynamically_import_QuantLinear
+from ._fused_base import FusedBaseAttentionModule
+
+
+def fixed_pos_embedding(x, seq_dim=1, seq_len=None):
+ dim = x.shape[-1]
+ if seq_len is None:
+ seq_len = x.shape[seq_dim]
+ inv_freq = 1.0 / (10000 ** (torch.arange(0, dim, 2) / dim))
+ sinusoid_inp = (
+ torch.einsum("i , j -> i j", torch.arange(seq_len, dtype=torch.float), inv_freq).to(x.device).float()
+ )
+ return torch.sin(sinusoid_inp), torch.cos(sinusoid_inp)
+
+
+def rotate_every_two(x):
+ x1 = x[:, :, :, ::2]
+ x2 = x[:, :, :, 1::2]
+ x = torch.stack((-x2, x1), dim=-1)
+ return x.flatten(-2) # in einsum notation: rearrange(x, '... d j -> ... (d j)')
+
+
+def duplicate_interleave(m):
+ """
+ A simple version of `torch.repeat_interleave` for duplicating a matrix while interleaving the copy.
+ """
+ dim0 = m.shape[0]
+ m = m.view(-1, 1) # flatten the matrix
+ m = m.repeat(1, 2) # repeat all elements into the 2nd dimension
+ m = m.view(dim0, -1) # reshape into a matrix, interleaving the copy
+ return m
+
+
+def apply_rotary_pos_emb(x, sincos, offset=0):
+ sin, cos = (duplicate_interleave(t)[None, offset : x.shape[1] + offset, None, :] for t in sincos)
+ # einsum notation for lambda t: repeat(t[offset:x.shape[1]+offset,:], "n d -> () n () (d j)", j=2)
+ return (x * cos) + (rotate_every_two(x) * sin)
+
+
+class FusedGPTJAttentionForQuantizedModel(FusedBaseAttentionModule):
+ def __init__(self, config):
+ super().__init__()
+
+ max_positions = config.max_position_embeddings
+ self.register_buffer(
+ "bias",
+ torch.tril(torch.ones((max_positions, max_positions), dtype=torch.bool)).view(
+ 1, 1, max_positions, max_positions
+ ),
+ )
+ self.register_buffer("masked_bias", torch.tensor(-1e9))
+
+ self.attn_dropout = nn.Dropout(config.attn_pdrop)
+ self.attn_dropout_p = config.attn_pdrop
+ self.resid_dropout = nn.Dropout(config.resid_pdrop)
+
+ self.embed_dim = config.hidden_size
+ self.num_attention_heads = config.num_attention_heads
+ self.head_dim = self.embed_dim // self.num_attention_heads
+ if self.head_dim * self.num_attention_heads != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_attention_heads (got `embed_dim`: {self.embed_dim} and"
+ f" `num_attention_heads`: {self.num_attention_heads})."
+ )
+ self.scale_attn = torch.sqrt(torch.tensor(self.head_dim, dtype=torch.float32)).to(torch.get_default_dtype())
+
+ self.qkv_proj = nn.Linear(self.embed_dim, self.embed_dim * 3, bias=False)
+ self.out_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=False)
+ self.rotary_dim = config.rotary_dim
+
+ def _split_heads(self, qkv):
+ """
+ Splits hidden dim into attn_head_size and num_attention_heads
+ """
+ new_shape = qkv.size()[:-1] + (3, self.num_attention_heads, self.head_dim)
+ qkv = qkv.view(new_shape) # (batch, seq_length, 3, head, head_features)
+ query = qkv[:, :, 0]
+ key = qkv[:, :, 1]
+ value = qkv[:, :, 2]
+
+ return query, key, value
+
+ def _merge_heads(self, tensor, num_attention_heads, attn_head_size):
+ """
+ Merges attn_head_size dim and num_attn_heads dim into hidden dim
+ """
+ if len(tensor.shape) == 5:
+ tensor = tensor.permute(0, 1, 3, 2, 4).contiguous()
+ elif len(tensor.shape) == 4:
+ tensor = tensor.permute(0, 2, 1, 3).contiguous()
+ else:
+ raise ValueError(f"Input tensor rank should be one of [4, 5], but is: {len(tensor.shape)}")
+ new_shape = tensor.size()[:-2] + (num_attention_heads * attn_head_size,)
+ return tensor.view(new_shape)
+
+ def _attn(
+ self,
+ query,
+ key,
+ value,
+ attention_mask=None,
+ head_mask=None,
+ ):
+ # compute causal mask from causal mask buffer
+ query_length, key_length = query.size(-2), key.size(-2)
+ causal_mask = self.bias[:, :, key_length - query_length : key_length, :key_length]
+
+ # Keep the attention weights computation in fp32 to avoid overflow issues
+ query = query.to(torch.float32)
+ key = key.to(torch.float32)
+
+ attn_weights = torch.matmul(query, key.transpose(-1, -2))
+
+ mask_value = torch.finfo(attn_weights.dtype).min
+ # Need to be a tensor, otherwise we get error: `RuntimeError: expected scalar type float but found double`.
+ # Need to be on the same device, otherwise `RuntimeError: ..., x and y to be on the same device`
+ mask_value = torch.tensor(mask_value, dtype=attn_weights.dtype).to(attn_weights.device)
+ attn_weights = torch.where(causal_mask, attn_weights, mask_value)
+
+ attn_weights = attn_weights / self.scale_attn
+
+ if attention_mask is not None:
+ # Apply the attention mask
+ attn_weights = attn_weights + attention_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1)
+ attn_weights = attn_weights.to(value.dtype)
+ attn_weights = self.attn_dropout(attn_weights)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attn_weights = attn_weights * head_mask
+
+ attn_output = torch.matmul(attn_weights, value)
+
+ return attn_output, attn_weights
+
+ def forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ layer_past: Optional[Tuple[torch.Tensor]] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = False,
+ output_attentions: Optional[bool] = False,
+ ) -> Union[
+ Tuple[torch.Tensor, Tuple[torch.Tensor]],
+ Optional[Tuple[torch.Tensor, Tuple[torch.Tensor], Tuple[torch.Tensor, ...]]],
+ ]:
+ query, key, value = self._split_heads(self.qkv_proj(hidden_states))
+
+ seq_len = key.shape[1]
+ offset = 0
+
+ if layer_past is not None:
+ offset = layer_past[0].shape[-2]
+ seq_len += offset
+
+ if self.rotary_dim is not None:
+ k_rot = key[:, :, :, : self.rotary_dim]
+ k_pass = key[:, :, :, self.rotary_dim :]
+
+ q_rot = query[:, :, :, : self.rotary_dim]
+ q_pass = query[:, :, :, self.rotary_dim :]
+
+ sincos = fixed_pos_embedding(k_rot, 1, seq_len=seq_len)
+ k_rot = apply_rotary_pos_emb(k_rot, sincos, offset=offset)
+ q_rot = apply_rotary_pos_emb(q_rot, sincos, offset=offset)
+
+ key = torch.cat([k_rot, k_pass], dim=-1)
+ query = torch.cat([q_rot, q_pass], dim=-1)
+ else:
+ sincos = fixed_pos_embedding(key, 1, seq_len=seq_len)
+ key = apply_rotary_pos_emb(key, sincos, offset=offset)
+ query = apply_rotary_pos_emb(query, sincos, offset=offset)
+
+ key = key.permute(0, 2, 1, 3)
+ query = query.permute(0, 2, 1, 3)
+ value = value.permute(0, 2, 1, 3)
+
+ is_causal = layer_past is None
+ if layer_past is not None:
+ past_key = layer_past[0]
+ past_value = layer_past[1]
+ key = torch.cat((past_key, key), dim=-2)
+ value = torch.cat((past_value, value), dim=-2)
+
+ if use_cache is True:
+ query = query.contiguous()
+ key = key.contiguous()
+ value = value.contiguous()
+ present = (key, value)
+ else:
+ present = None
+
+ # compute self-attention: V x Softmax(QK^T)
+ if compare_pytorch_version("v2.0.0", op="ge"):
+ attn_output = F.scaled_dot_product_attention(
+ query,
+ key,
+ value,
+ attn_mask=None if is_causal else attention_mask,
+ dropout_p=self.attn_dropout_p,
+ is_causal=is_causal,
+ )
+ attn_weights = None
+ else:
+ attn_output, attn_weights = self._attn(query, key, value, attention_mask, head_mask)
+
+ attn_output = self._merge_heads(attn_output, self.num_attention_heads, self.head_dim)
+ attn_output = self.out_proj(attn_output)
+ attn_output = self.resid_dropout(attn_output)
+
+ outputs = (attn_output, present)
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs # a, present, (attentions)
+
+ @classmethod
+ def inject_to_model(
+ cls,
+ model,
+ use_triton=False,
+ group_size=-1,
+ use_cuda_fp16=True,
+ desc_act=False,
+ trainable=False,
+ bits: int = 4,
+ disable_exllama=True,
+ disable_exllamav2=False,
+ **kwargs,
+ ):
+ config = model.config
+ QuantLinear = dynamically_import_QuantLinear(
+ use_triton=use_triton,
+ desc_act=desc_act,
+ group_size=group_size,
+ bits=bits,
+ disable_exllama=disable_exllama,
+ disable_exllamav2=disable_exllamav2,
+ )
+
+ for name, m in model.named_modules():
+ if not isinstance(m, GPTJAttention):
+ continue
+
+ attn = cls(config).to(device=next(m.buffers()).device)
+
+ q_proj = m.q_proj
+ k_proj = m.k_proj
+ v_proj = m.v_proj
+
+ qweights = torch.cat([q_proj.qweight, k_proj.qweight, v_proj.qweight], dim=1)
+ qzeros = torch.cat([q_proj.qzeros, k_proj.qzeros, v_proj.qzeros], dim=1)
+ scales = torch.cat([q_proj.scales, k_proj.scales, v_proj.scales], dim=1)
+
+ if QuantLinear.QUANT_TYPE == "exllama":
+ if desc_act:
+ # See fused_llama_attn.py comment
+ raise ValueError(
+ "Exllama kernel does not support query/key/value fusion with act-order. Please either use inject_fused_attention=False or disable_exllama=True."
+ )
+ else:
+ g_idx = None
+ else:
+ g_idx = torch.cat([q_proj.g_idx, k_proj.g_idx, v_proj.g_idx], dim=0)
+
+ bias = torch.cat([q_proj.bias, k_proj.bias, v_proj.bias], dim=0) if q_proj.bias is not None else None
+
+ qlinear_args = (
+ q_proj.bits,
+ q_proj.group_size,
+ q_proj.infeatures,
+ q_proj.outfeatures + k_proj.outfeatures + v_proj.outfeatures,
+ True if q_proj.bias is not None else False,
+ )
+ qlinear_kwargs = {"trainable": trainable}
+ if (not desc_act or group_size == -1) and not use_triton:
+ qlinear_kwargs["use_cuda_fp16"] = use_cuda_fp16
+ qlinear_kwargs["weight_dtype"] = q_proj.scales.dtype
+
+ qkv_proj = QuantLinear(*qlinear_args, **qlinear_kwargs)
+ qkv_proj.qweight = qweights
+ qkv_proj.qzeros = qzeros
+ qkv_proj.scales = scales
+ qkv_proj.g_idx = g_idx
+ qkv_proj.bias = bias
+
+ if "." in name:
+ parent_name = name.rsplit(".", 1)[0]
+ child_name = name[len(parent_name) + 1 :]
+ parent = model.get_submodule(parent_name)
+ else:
+ parent_name = ""
+ parent = model
+ child_name = name
+
+ attn.qkv_proj = qkv_proj
+ attn.out_proj = m.out_proj
+
+ setattr(parent, child_name, attn)
+ del m
+
+
+__all__ = ["FusedGPTJAttentionForQuantizedModel"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/fused_llama_attn.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/fused_llama_attn.py
new file mode 100644
index 0000000000000000000000000000000000000000..a2cde1b65f48456964b7166bcad1345fb65aa917
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/fused_llama_attn.py
@@ -0,0 +1,234 @@
+import math
+
+import torch
+import torch.nn as nn
+from torch.nn import functional as F
+from transformers.models.llama.modeling_llama import (
+ LlamaAttention,
+ apply_rotary_pos_emb,
+)
+
+from ..utils.import_utils import compare_pytorch_version, dynamically_import_QuantLinear
+from ._fused_base import FusedBaseAttentionModule
+
+
+class FusedLlamaAttentionForQuantizedModel(FusedBaseAttentionModule):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(
+ self,
+ hidden_size,
+ num_heads,
+ qkv_proj,
+ o_proj,
+ rotary_emb,
+ layer_idx,
+ ):
+ super().__init__()
+ self.hidden_size = hidden_size
+ self.num_heads = num_heads
+ self.head_dim = hidden_size // num_heads
+ self.layer_idx = layer_idx
+
+ if self.head_dim * num_heads != self.hidden_size:
+ raise ValueError(
+ f"hidden_size must be divisible by num_heads (got `hidden_size`: {self.hidden_size}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.qkv_proj = qkv_proj
+ self.o_proj = o_proj
+ self.rotary_emb = rotary_emb
+
+ def _shape(self, tensor, seq_len, bsz):
+ return tensor.view(bsz, seq_len, self.num_heads, self.head_dim).transpose(1, 2).contiguous()
+
+ def forward(
+ self,
+ hidden_states,
+ past_key_value=None,
+ attention_mask=None,
+ position_ids=None,
+ output_attentions=False,
+ use_cache=False,
+ **kwargs,
+ ):
+ """Input shape: Batch x Time x Channel"""
+
+ bsz, q_len, _ = hidden_states.size()
+
+ qkv_states = self.qkv_proj(hidden_states)
+ query_states, key_states, value_states = torch.split(qkv_states, self.hidden_size, dim=2)
+
+ query_states = query_states.view(bsz, q_len, self.num_heads, self.head_dim).transpose(1, 2)
+ key_states = key_states.view(bsz, q_len, self.num_heads, self.head_dim).transpose(1, 2)
+ value_states = value_states.view(bsz, q_len, self.num_heads, self.head_dim).transpose(1, 2)
+
+ kv_seq_len = key_states.shape[-2]
+ if past_key_value is not None:
+ if self.layer_idx is None:
+ raise ValueError(
+ f"The cache structure has changed since version v4.36. If you are using {self.__class__.__name__} "
+ "for auto-regressive decoding with k/v caching, please make sure to initialize the attention class "
+ "with a layer index. Please open an issue in AutoGPTQ if you hit this."
+ )
+ kv_seq_len += past_key_value.get_usable_length(kv_seq_len, self.layer_idx)
+
+ cos, sin = self.rotary_emb(value_states, seq_len=kv_seq_len)
+ query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin, position_ids)
+ # [bsz, nh, t, hd]
+
+ if past_key_value is not None:
+ cache_kwargs = {"sin": sin, "cos": cos} # Specific to RoPE models
+ key_states, value_states = past_key_value.update(key_states, value_states, self.layer_idx, cache_kwargs)
+
+ if use_cache:
+ # Since qkv_proj is fused, query_states etc will hold a reference to the original qkv_states tensor
+ # which can cause excessive memory usage by the cache. `contiguous` is a convenient way to workaround this.
+ query_states = query_states.contiguous()
+ key_states = key_states.contiguous()
+ value_states = value_states.contiguous()
+
+ if compare_pytorch_version("v2.0.0", op="ge"):
+ attn_output = F.scaled_dot_product_attention(
+ query_states,
+ key_states,
+ value_states,
+ attn_mask=attention_mask,
+ is_causal=attention_mask is None and q_len > 1,
+ )
+ attn_weights = None
+ else:
+ attn_weights = torch.matmul(query_states, key_states.transpose(2, 3)) / math.sqrt(self.head_dim)
+
+ if attn_weights.size() != (bsz, self.num_heads, q_len, kv_seq_len):
+ raise ValueError(
+ f"Attention weights should be of size {(bsz * self.num_heads, q_len, kv_seq_len)}, but is"
+ f" {attn_weights.size()}"
+ )
+
+ if attention_mask is not None:
+ if attention_mask.size() != (bsz, 1, q_len, kv_seq_len):
+ raise ValueError(
+ f"Attention mask should be of size {(bsz, 1, q_len, kv_seq_len)}, but is {attention_mask.size()}"
+ )
+ attn_weights = attn_weights + attention_mask
+ attn_weights = torch.max(attn_weights, torch.tensor(torch.finfo(attn_weights.dtype).min))
+
+ # upcast attention to fp32
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query_states.dtype)
+ attn_output = torch.matmul(attn_weights, value_states)
+
+ if attn_output.size() != (bsz, self.num_heads, q_len, self.head_dim):
+ raise ValueError(
+ f"`attn_output` should be of size {(bsz, self.num_heads, q_len, self.head_dim)}, but is"
+ f" {attn_output.size()}"
+ )
+
+ attn_output = attn_output.transpose(1, 2)
+ attn_output = attn_output.reshape(bsz, q_len, self.hidden_size)
+
+ attn_output = self.o_proj(attn_output)
+
+ if not output_attentions:
+ attn_weights = None
+
+ return attn_output, attn_weights, past_key_value
+
+ @classmethod
+ def inject_to_model(
+ cls,
+ model,
+ use_triton=False,
+ group_size=-1,
+ use_cuda_fp16=True,
+ desc_act=False,
+ trainable=False,
+ bits: int = 4,
+ disable_exllama=True,
+ disable_exllamav2=False,
+ **kwargs,
+ ):
+ """
+ Replace all LlamaAttention modules with QuantLlamaAttention modules, fusing the q, k, v projections.
+ """
+ QuantLinear = dynamically_import_QuantLinear(
+ use_triton=use_triton,
+ desc_act=desc_act,
+ group_size=group_size,
+ bits=bits,
+ disable_exllama=disable_exllama,
+ disable_exllamav2=disable_exllamav2,
+ )
+
+ for name, m in model.named_modules():
+ if not isinstance(m, LlamaAttention):
+ continue
+
+ q_proj = m.q_proj
+ k_proj = m.k_proj
+ v_proj = m.v_proj
+
+ qweights = torch.cat([q_proj.qweight, k_proj.qweight, v_proj.qweight], dim=1)
+ qzeros = torch.cat([q_proj.qzeros, k_proj.qzeros, v_proj.qzeros], dim=1)
+ scales = torch.cat([q_proj.scales, k_proj.scales, v_proj.scales], dim=1)
+
+ if QuantLinear.QUANT_TYPE == "exllama":
+ if desc_act:
+ # TODO: support it. The issue lies maybe in the line:
+ # int groups = qzeros.size(0);
+ # in exllama_ext.cpp
+ raise ValueError(
+ "Exllama kernel does not support query/key/value fusion with act-order. Please either use inject_fused_attention=False or disable_exllama=True."
+ )
+ else:
+ g_idx = None
+ else:
+ g_idx = torch.cat([q_proj.g_idx, k_proj.g_idx, v_proj.g_idx], dim=0)
+
+ bias = torch.cat([q_proj.bias, k_proj.bias, v_proj.bias], dim=0) if q_proj.bias is not None else None
+
+ qlinear_args = (
+ q_proj.bits,
+ q_proj.group_size,
+ q_proj.infeatures,
+ q_proj.outfeatures + k_proj.outfeatures + v_proj.outfeatures,
+ True if q_proj.bias is not None else False,
+ )
+ qlinear_kwargs = {"trainable": trainable}
+ if (not desc_act or group_size == -1) and not use_triton:
+ qlinear_kwargs["use_cuda_fp16"] = use_cuda_fp16
+ qlinear_kwargs["weight_dtype"] = q_proj.scales.dtype
+
+ qkv_layer = QuantLinear(*qlinear_args, **qlinear_kwargs)
+ qkv_layer.qweight = qweights
+ qkv_layer.qzeros = qzeros
+ qkv_layer.scales = scales
+ qkv_layer.g_idx = g_idx
+ qkv_layer.bias = bias
+
+ # Introduced in Transformers 4.36
+ layer_idx = None
+ if hasattr(m, "layer_idx"):
+ layer_idx = m.layer_idx
+ attn = cls(
+ m.hidden_size,
+ m.num_heads,
+ qkv_layer,
+ m.o_proj,
+ m.rotary_emb,
+ layer_idx=layer_idx,
+ )
+
+ if "." in name:
+ parent_name = name.rsplit(".", 1)[0]
+ child_name = name[len(parent_name) + 1 :]
+ parent = model.get_submodule(parent_name)
+ else:
+ parent_name = ""
+ parent = model
+ child_name = name
+
+ setattr(parent, child_name, attn)
+
+
+__all__ = ["FusedLlamaAttentionForQuantizedModel"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/fused_llama_mlp.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/fused_llama_mlp.py
new file mode 100644
index 0000000000000000000000000000000000000000..f20df0d0226678565d2a24e319785ea74bc03d82
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/fused_llama_mlp.py
@@ -0,0 +1,365 @@
+import math
+from logging import getLogger
+
+import torch
+from transformers.models.llama.modeling_llama import LlamaMLP
+
+from ..utils.import_utils import TRITON_AVAILABLE
+from ._fused_base import FusedBaseMLPModule
+
+
+logger = getLogger(__name__)
+
+if TRITON_AVAILABLE:
+ import triton
+ import triton.language as tl
+
+ from .triton_utils import custom_autotune
+ from .triton_utils.kernels import silu
+
+ @custom_autotune.autotune(
+ configs=[
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 256,
+ "BLOCK_SIZE_N": 64,
+ "BLOCK_SIZE_K": 32,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ),
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 64,
+ "BLOCK_SIZE_N": 256,
+ "BLOCK_SIZE_K": 32,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ),
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 128,
+ "BLOCK_SIZE_N": 128,
+ "BLOCK_SIZE_K": 32,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ),
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 128,
+ "BLOCK_SIZE_N": 64,
+ "BLOCK_SIZE_K": 32,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ),
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 64,
+ "BLOCK_SIZE_N": 128,
+ "BLOCK_SIZE_K": 32,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ),
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 128,
+ "BLOCK_SIZE_N": 32,
+ "BLOCK_SIZE_K": 32,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ), # 3090
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 128,
+ "BLOCK_SIZE_N": 16,
+ "BLOCK_SIZE_K": 32,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ), # 3090
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 32,
+ "BLOCK_SIZE_N": 32,
+ "BLOCK_SIZE_K": 128,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=2,
+ num_warps=4,
+ ), # 3090
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 64,
+ "BLOCK_SIZE_N": 16,
+ "BLOCK_SIZE_K": 64,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ), # 3090
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 64,
+ "BLOCK_SIZE_N": 32,
+ "BLOCK_SIZE_K": 64,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ), # 3090
+ ],
+ key=["M", "N", "K"],
+ nearest_power_of_two=True,
+ prune_configs_by={
+ "early_config_prune": custom_autotune.matmul248_kernel_config_pruner,
+ "perf_model": None,
+ "top_k": None,
+ },
+ )
+ @triton.jit
+ def quant_fused_matmul_248_kernel(
+ a_ptr,
+ c_ptr,
+ b1_ptr,
+ scales1_ptr,
+ zeros1_ptr,
+ g1_ptr,
+ b2_ptr,
+ scales2_ptr,
+ zeros2_ptr,
+ g2_ptr,
+ M,
+ N,
+ K,
+ bits,
+ maxq,
+ stride_am,
+ stride_ak,
+ stride_bk,
+ stride_bn,
+ stride_cm,
+ stride_cn,
+ stride_scales,
+ stride_zeros,
+ BLOCK_SIZE_M: tl.constexpr,
+ BLOCK_SIZE_N: tl.constexpr,
+ BLOCK_SIZE_K: tl.constexpr,
+ GROUP_SIZE_M: tl.constexpr,
+ ):
+ """
+ Computes: C = silu(A * B1) * (A * B2)
+ A is of shape (M, K) float16
+ B is of shape (K//8, N) int32
+ C is of shape (M, N) float16
+ scales is of shape (1, N) float16
+ zeros is of shape (1, N//8) int32
+ """
+ infearure_per_bits = 32 // bits
+
+ pid = tl.program_id(axis=0)
+ num_pid_m = tl.cdiv(M, BLOCK_SIZE_M)
+ num_pid_n = tl.cdiv(N, BLOCK_SIZE_N)
+ num_pid_k = tl.cdiv(K, BLOCK_SIZE_K)
+ num_pid_in_group = GROUP_SIZE_M * num_pid_n
+ group_id = pid // num_pid_in_group
+ first_pid_m = group_id * GROUP_SIZE_M
+ group_size_m = min(num_pid_m - first_pid_m, GROUP_SIZE_M)
+ pid_m = first_pid_m + (pid % group_size_m)
+ pid_n = (pid % num_pid_in_group) // group_size_m
+
+ offs_am = pid_m * BLOCK_SIZE_M + tl.arange(0, BLOCK_SIZE_M)
+ offs_bn = pid_n * BLOCK_SIZE_N + tl.arange(0, BLOCK_SIZE_N)
+ offs_k = tl.arange(0, BLOCK_SIZE_K)
+ a_ptrs = a_ptr + (offs_am[:, None] * stride_am + offs_k[None, :] * stride_ak) # (BLOCK_SIZE_M, BLOCK_SIZE_K)
+ a_mask = offs_am[:, None] < M
+ # b_ptrs is set up such that it repeats elements along the K axis 8 times
+ b1_ptrs = b1_ptr + ((offs_k[:, None] // infearure_per_bits) * stride_bk + offs_bn[None, :] * stride_bn)
+ b2_ptrs = b2_ptr + ((offs_k[:, None] // infearure_per_bits) * stride_bk + offs_bn[None, :] * stride_bn)
+ g1_ptrs = g1_ptr + offs_k
+ g2_ptrs = g2_ptr + offs_k
+ # shifter is used to extract the N bits of each element in the 32-bit word from B
+ scales1_ptrs = scales1_ptr + offs_bn[None, :]
+ scales2_ptrs = scales2_ptr + offs_bn[None, :]
+ zeros1_ptrs = zeros1_ptr + (offs_bn[None, :] // infearure_per_bits)
+ zeros2_ptrs = zeros2_ptr + (offs_bn[None, :] // infearure_per_bits)
+
+ shifter = (offs_k % infearure_per_bits) * bits
+ zeros_shifter = (offs_bn % infearure_per_bits) * bits
+ accumulator1 = tl.zeros((BLOCK_SIZE_M, BLOCK_SIZE_N), dtype=tl.float32)
+ accumulator2 = tl.zeros((BLOCK_SIZE_M, BLOCK_SIZE_N), dtype=tl.float32)
+ for k in range(0, num_pid_k):
+ g1_idx = tl.load(g1_ptrs)
+ g2_idx = tl.load(g2_ptrs)
+
+ # Fetch scales and zeros; these are per-outfeature and thus reused in the inner loop
+ scales1 = tl.load(scales1_ptrs + g1_idx[:, None] * stride_scales) # (BLOCK_SIZE_K, BLOCK_SIZE_N,)
+ scales2 = tl.load(scales2_ptrs + g2_idx[:, None] * stride_scales)
+
+ zeros1 = tl.load(zeros1_ptrs + g1_idx[:, None] * stride_zeros) # (BLOCK_SIZE_K, BLOCK_SIZE_N,)
+ zeros1 = (zeros1 >> zeros_shifter[None, :]) & maxq
+ zeros1 = zeros1 + 1
+
+ zeros2 = tl.load(zeros2_ptrs + g2_idx[:, None] * stride_zeros) # (BLOCK_SIZE_K, BLOCK_SIZE_N,)
+ zeros2 = (zeros2 >> zeros_shifter[None, :]) & maxq
+ zeros2 = zeros2 + 1
+
+ a = tl.load(a_ptrs, mask=a_mask, other=0.0) # (BLOCK_SIZE_M, BLOCK_SIZE_K)
+ b1 = tl.load(b1_ptrs) # (BLOCK_SIZE_K, BLOCK_SIZE_N), but repeated
+ b2 = tl.load(b2_ptrs)
+
+ # Now we need to unpack b (which is N-bit values) into 32-bit values
+ b1 = (b1 >> shifter[:, None]) & maxq # Extract the N-bit values
+ b1 = (b1 - zeros1) * scales1 # Scale and shift
+ accumulator1 += tl.dot(a, b1)
+
+ b2 = (b2 >> shifter[:, None]) & maxq
+ b2 = (b2 - zeros2) * scales2
+ accumulator2 += tl.dot(a, b2)
+
+ a_ptrs += BLOCK_SIZE_K
+ b1_ptrs += (BLOCK_SIZE_K // infearure_per_bits) * stride_bk
+ b2_ptrs += (BLOCK_SIZE_K // infearure_per_bits) * stride_bk
+ g1_ptrs += BLOCK_SIZE_K
+ g2_ptrs += BLOCK_SIZE_K
+
+ accumulator1 = silu(accumulator1)
+ c = accumulator1 * accumulator2
+ c = c.to(tl.float16)
+ c_ptrs = c_ptr + stride_cm * offs_am[:, None] + stride_cn * offs_bn[None, :]
+ c_mask = (offs_am[:, None] < M) & (offs_bn[None, :] < N)
+ tl.store(c_ptrs, c, mask=c_mask)
+
+else:
+ quant_fused_matmul_248_kernel = None
+
+
+class FusedLlamaMLPForQuantizedModel(FusedBaseMLPModule):
+ def __init__(
+ self,
+ gate_proj,
+ down_proj,
+ up_proj,
+ ):
+ super().__init__()
+
+ self.infeatures = gate_proj.infeatures
+ self.intermediate_size = gate_proj.outfeatures
+ self.outfeatures = down_proj.outfeatures
+ self.bits = gate_proj.bits
+ self.maxq = gate_proj.maxq
+
+ self.gate_proj = gate_proj
+ self.up_proj = up_proj
+ self.down_proj = down_proj
+
+ def forward(self, x):
+ return self.down_proj(self.triton_llama_mlp(x))
+
+ def triton_llama_mlp(self, x):
+ with torch.cuda.device(x.device):
+ out_shape = x.shape[:-1] + (self.intermediate_size,)
+ x = x.reshape(-1, x.shape[-1])
+ M, K = x.shape
+ N = self.intermediate_size
+ c = torch.empty((M, N), device=x.device, dtype=torch.float16)
+ grid = lambda META: ( # noqa: E731
+ triton.cdiv(M, META["BLOCK_SIZE_M"]) * triton.cdiv(N, META["BLOCK_SIZE_N"]),
+ )
+ quant_fused_matmul_248_kernel[grid](
+ x,
+ c,
+ self.gate_proj.qweight,
+ self.gate_proj.scales,
+ self.gate_proj.qzeros,
+ self.gate_proj.g_idx,
+ self.up_proj.qweight,
+ self.up_proj.scales,
+ self.up_proj.qzeros,
+ self.up_proj.g_idx,
+ M,
+ N,
+ K,
+ self.bits,
+ self.maxq,
+ x.stride(0),
+ x.stride(1),
+ self.gate_proj.qweight.stride(0),
+ self.gate_proj.qweight.stride(1),
+ c.stride(0),
+ c.stride(1),
+ self.gate_proj.scales.stride(0),
+ self.gate_proj.qzeros.stride(0),
+ )
+ c = c.reshape(out_shape)
+ return c
+
+ @classmethod
+ def inject_to_model(cls, model, use_triton=False, **kwargs):
+ if not use_triton:
+ logger.warning(
+ f"Skipping module injection for {cls.__name__} as currently not supported with use_triton=False."
+ )
+ return
+ elif not TRITON_AVAILABLE:
+ logger.warning(
+ f"Skipping module injection for {cls.__name__} as Triton is not available. Please check your installation."
+ )
+ return
+
+ for name, m in model.named_modules():
+ if not isinstance(m, LlamaMLP):
+ continue
+
+ mlp = cls(m.gate_proj, m.down_proj, m.up_proj)
+
+ if "." in name:
+ parent_name = name.rsplit(".", 1)[0]
+ child_name = name[len(parent_name) + 1 :]
+ parent = model.get_submodule(parent_name)
+ else:
+ parent_name = ""
+ parent = model
+ child_name = name
+
+ setattr(parent, child_name, mlp)
+
+ @classmethod
+ def warmup(cls, model, transpose=False, seqlen=2048):
+ from tqdm import tqdm
+
+ kn_values = {}
+
+ for _, m in model.named_modules():
+ if not isinstance(m, cls):
+ continue
+
+ k = m.infeatures
+ n = m.intermediate_size
+
+ if (k, n) not in kn_values:
+ kn_values[(k, n)] = m
+
+ logger.info(f"Found {len(kn_values)} unique fused mlp KN values.")
+ logger.info("Warming up autotune cache ...")
+ with torch.no_grad():
+ for m in tqdm(range(0, math.ceil(math.log2(seqlen)) + 1)):
+ m = 2**m
+ for (k, n), (modules) in kn_values.items():
+ a = torch.randn(m, k, dtype=torch.float16, device=model.device)
+ modules.triton_llama_mlp(a)
+ del kn_values
+
+
+__all__ = ["FusedLlamaMLPForQuantizedModel"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/__init__.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..0e0737a04ee820d98ca9cd6f126b9a8adc99f0c3
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/__init__.py
@@ -0,0 +1,56 @@
+import torch.nn as nn
+
+
+class GeneralQuantLinear(nn.Linear):
+ def __init__(self, quant_linear_module):
+ super().__init__(
+ in_features=quant_linear_module.infeatures,
+ out_features=quant_linear_module.outfeatures,
+ bias=True,
+ )
+ self.infeatures = quant_linear_module.infeatures
+ self.outfeatures = quant_linear_module.outfeatures
+ self.bits = quant_linear_module.bits
+ self.group_size = quant_linear_module.group_size
+ self.maxq = quant_linear_module.maxq
+
+ self.weight.requires_grad = False
+
+ self.weight.data = quant_linear_module.qweight
+ self.register_buffer("qweight", quant_linear_module.qweight)
+ self.bias.data = quant_linear_module.bias
+
+ self.qweight.requires_grad = False
+ self.bias.requires_grad = False
+
+ self.register_buffer("qzeros", quant_linear_module.qzeros)
+ self.register_buffer("scales", quant_linear_module.scales)
+ self.register_buffer("g_idx", quant_linear_module.g_idx)
+
+ if hasattr(quant_linear_module, "wf"):
+ self.wf = quant_linear_module.wf
+ if hasattr(quant_linear_module, "kernel_switch_threshold"):
+ self.kernel_switch_threshold = quant_linear_module.kernel_switch_threshold
+ if hasattr(quant_linear_module, "autogptq_cuda_available"):
+ self.autogptq_cuda_available = quant_linear_module.autogptq_cuda_available
+
+ self.trainable = quant_linear_module.trainable
+
+ self.forward = quant_linear_module.forward
+
+ @classmethod
+ def inject_to_model(cls, model, target_module_type):
+ for name, m in model.named_modules():
+ if not isinstance(m, target_module_type):
+ continue
+ new_m = cls(m)
+ if "." in name:
+ parent_name = name.rsplit(".", 1)[0]
+ child_name = name[len(parent_name) + 1 :]
+ parent = model.get_submodule(parent_name)
+ else:
+ parent_name = ""
+ parent = model
+ child_name = name
+
+ setattr(parent, child_name, new_m)
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_cuda.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_cuda.py
new file mode 100644
index 0000000000000000000000000000000000000000..b73b639493f30cc391a6c26f8c019019837508b1
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_cuda.py
@@ -0,0 +1,320 @@
+import math
+from logging import getLogger
+
+import numpy as np
+import torch
+import torch.nn as nn
+import transformers
+
+
+logger = getLogger(__name__)
+
+try:
+ import autogptq_cuda_64
+ import autogptq_cuda_256
+
+ _autogptq_cuda_available = True
+except ImportError:
+ logger.warning("CUDA extension not installed.")
+ autogptq_cuda_256 = None
+ autogptq_cuda_64 = None
+ _autogptq_cuda_available = False
+
+
+class QuantLinear(nn.Module):
+ QUANT_TYPE = "cuda"
+
+ def __init__(
+ self,
+ bits,
+ group_size,
+ infeatures,
+ outfeatures,
+ bias,
+ kernel_switch_threshold=128,
+ trainable=False,
+ weight_dtype=torch.float16,
+ ):
+ super().__init__()
+ global _autogptq_cuda_available
+ if bits not in [2, 3, 4, 8]:
+ raise NotImplementedError("Only 2,3,4,8 bits are supported.")
+ if trainable:
+ _autogptq_cuda_available = False
+
+ self.infeatures = infeatures
+ self.outfeatures = outfeatures
+ self.bits = bits
+ self.group_size = group_size if group_size != -1 else infeatures
+ self.maxq = 2**self.bits - 1
+
+ self.register_buffer(
+ "qweight",
+ torch.zeros((infeatures // 32 * self.bits, outfeatures), dtype=torch.int32),
+ )
+ self.register_buffer(
+ "qzeros",
+ torch.zeros(
+ (
+ math.ceil(infeatures / self.group_size),
+ outfeatures // 32 * self.bits,
+ ),
+ dtype=torch.int32,
+ ),
+ )
+ self.register_buffer(
+ "scales",
+ torch.zeros(
+ (math.ceil(infeatures / self.group_size), outfeatures),
+ dtype=weight_dtype,
+ ),
+ )
+ self.register_buffer(
+ "g_idx",
+ torch.tensor([i // self.group_size for i in range(infeatures)], dtype=torch.int32),
+ )
+ if bias:
+ self.register_buffer("bias", torch.zeros((outfeatures), dtype=weight_dtype))
+ else:
+ self.bias = None
+
+ # is performed by unpacking the weights and using torch.matmul
+ if self.bits in [2, 4, 8]:
+ self.wf = torch.tensor(list(range(0, 32, self.bits)), dtype=torch.int32).unsqueeze(0)
+ elif self.bits == 3:
+ self.wf = torch.tensor(
+ [
+ [0, 3, 6, 9, 12, 15, 18, 21, 24, 27, 30, 0],
+ [0, 1, 4, 7, 10, 13, 16, 19, 22, 25, 28, 31],
+ [0, 2, 5, 8, 11, 14, 17, 20, 23, 26, 29, 0],
+ ],
+ dtype=torch.int32,
+ ).reshape(1, 3, 12)
+
+ self.kernel_switch_threshold = kernel_switch_threshold
+ self.autogptq_cuda_available = _autogptq_cuda_available
+
+ self.autogptq_cuda = autogptq_cuda_256
+ if infeatures % 256 != 0 or outfeatures % 256 != 0:
+ self.autogptq_cuda = autogptq_cuda_64
+ if infeatures % 64 != 0 or outfeatures % 64 != 0:
+ self.autogptq_cuda_available = False
+
+ self.trainable = trainable
+
+ def post_init(self):
+ pass
+
+ def pack(self, linear, scales, zeros, g_idx=None):
+ W = linear.weight.data.clone()
+ if isinstance(linear, nn.Conv2d):
+ W = W.flatten(1)
+ if isinstance(linear, transformers.pytorch_utils.Conv1D):
+ W = W.t()
+
+ self.g_idx = g_idx.clone() if g_idx is not None else self.g_idx
+
+ scales = scales.t().contiguous()
+ zeros = zeros.t().contiguous()
+ scale_zeros = zeros * scales
+ self.scales = scales.clone().to(dtype=linear.weight.dtype)
+ if linear.bias is not None:
+ self.bias = linear.bias.clone().to(dtype=linear.weight.dtype)
+
+ intweight = []
+ for idx in range(self.infeatures):
+ intweight.append(
+ torch.round((W[:, idx] + scale_zeros[self.g_idx[idx]]) / self.scales[self.g_idx[idx]]).to(torch.int)[
+ :, None
+ ]
+ )
+ intweight = torch.cat(intweight, dim=1)
+ intweight = intweight.t().contiguous()
+ intweight = intweight.numpy().astype(np.uint32)
+
+ i = 0
+ row = 0
+ qweight = np.zeros((intweight.shape[0] // 32 * self.bits, intweight.shape[1]), dtype=np.uint32)
+ while row < qweight.shape[0]:
+ if self.bits in [2, 4, 8]:
+ for j in range(i, i + (32 // self.bits)):
+ qweight[row] |= intweight[j] << (self.bits * (j - i))
+ i += 32 // self.bits
+ row += 1
+ elif self.bits == 3:
+ for j in range(i, i + 10):
+ qweight[row] |= intweight[j] << (3 * (j - i))
+ i += 10
+ qweight[row] |= intweight[i] << 30
+ row += 1
+ qweight[row] |= (intweight[i] >> 2) & 1
+ i += 1
+ for j in range(i, i + 10):
+ qweight[row] |= intweight[j] << (3 * (j - i) + 1)
+ i += 10
+ qweight[row] |= intweight[i] << 31
+ row += 1
+ qweight[row] |= (intweight[i] >> 1) & 0x3
+ i += 1
+ for j in range(i, i + 10):
+ qweight[row] |= intweight[j] << (3 * (j - i) + 2)
+ i += 10
+ row += 1
+ else:
+ raise NotImplementedError("Only 2,3,4,8 bits are supported.")
+
+ qweight = qweight.astype(np.int32)
+ self.qweight = torch.from_numpy(qweight)
+
+ zeros -= 1
+ zeros = zeros.numpy().astype(np.uint32)
+ qzeros = np.zeros((zeros.shape[0], zeros.shape[1] // 32 * self.bits), dtype=np.uint32)
+ i = 0
+ col = 0
+ while col < qzeros.shape[1]:
+ if self.bits in [2, 4, 8]:
+ for j in range(i, i + (32 // self.bits)):
+ qzeros[:, col] |= zeros[:, j] << (self.bits * (j - i))
+ i += 32 // self.bits
+ col += 1
+ elif self.bits == 3:
+ for j in range(i, i + 10):
+ qzeros[:, col] |= zeros[:, j] << (3 * (j - i))
+ i += 10
+ qzeros[:, col] |= zeros[:, i] << 30
+ col += 1
+ qzeros[:, col] |= (zeros[:, i] >> 2) & 1
+ i += 1
+ for j in range(i, i + 10):
+ qzeros[:, col] |= zeros[:, j] << (3 * (j - i) + 1)
+ i += 10
+ qzeros[:, col] |= zeros[:, i] << 31
+ col += 1
+ qzeros[:, col] |= (zeros[:, i] >> 1) & 0x3
+ i += 1
+ for j in range(i, i + 10):
+ qzeros[:, col] |= zeros[:, j] << (3 * (j - i) + 2)
+ i += 10
+ col += 1
+ else:
+ raise NotImplementedError("Only 2,3,4,8 bits are supported.")
+
+ qzeros = qzeros.astype(np.int32)
+ self.qzeros = torch.from_numpy(qzeros)
+
+ def forward(self, x: torch.Tensor):
+ out_shape = x.shape[:-1] + (self.outfeatures,)
+ x = x.reshape(-1, x.shape[-1])
+ x_dtype = x.dtype
+ if (
+ x.device.type == "cuda"
+ and self.autogptq_cuda_available
+ and (self.kernel_switch_threshold == 0 or x.shape[0] < self.kernel_switch_threshold)
+ ):
+ out = torch.zeros((x.shape[0], self.outfeatures), device=x.device, dtype=torch.float32)
+ if self.bits == 2:
+ self.autogptq_cuda.vecquant2matmul(
+ x.float(),
+ self.qweight,
+ out,
+ self.scales.float(),
+ self.qzeros,
+ self.g_idx,
+ )
+ elif self.bits == 3:
+ self.autogptq_cuda.vecquant3matmul(
+ x.float(),
+ self.qweight,
+ out,
+ self.scales.float(),
+ self.qzeros,
+ self.g_idx,
+ )
+ elif self.bits == 4:
+ self.autogptq_cuda.vecquant4matmul(
+ x.float(),
+ self.qweight,
+ out,
+ self.scales.float(),
+ self.qzeros,
+ self.g_idx,
+ )
+ elif self.bits == 8:
+ self.autogptq_cuda.vecquant8matmul(
+ x.float(),
+ self.qweight,
+ out,
+ self.scales.float(),
+ self.qzeros,
+ self.g_idx,
+ )
+ else:
+ raise NotImplementedError("Only 2,3,4,8 bits are supported.")
+ else:
+ if self.wf.device != self.qzeros.device:
+ self.wf = self.wf.to(self.qzeros.device)
+
+ if self.bits in [2, 4, 8]:
+ zeros = torch.bitwise_right_shift(
+ torch.unsqueeze(self.qzeros, 2).expand(-1, -1, 32 // self.bits),
+ self.wf.unsqueeze(0),
+ ).to(torch.int16 if self.bits == 8 else torch.int8)
+ zeros = torch.bitwise_and(zeros, (2**self.bits) - 1)
+
+ zeros = zeros + 1
+ zeros = zeros.reshape(self.scales.shape)
+
+ weight = torch.bitwise_right_shift(
+ torch.unsqueeze(self.qweight, 1).expand(-1, 32 // self.bits, -1),
+ self.wf.unsqueeze(-1),
+ ).to(torch.int16 if self.bits == 8 else torch.int8)
+ weight = torch.bitwise_and(weight, (2**self.bits) - 1)
+ elif self.bits == 3:
+ zeros = self.qzeros.reshape(self.qzeros.shape[0], self.qzeros.shape[1] // 3, 3, 1).expand(
+ -1, -1, -1, 12
+ )
+ zeros = zeros >> self.wf.unsqueeze(0)
+ zeros[:, :, 0, 10] = (zeros[:, :, 0, 10] & 0x3) | ((zeros[:, :, 1, 0] << 2) & 0x4)
+ zeros[:, :, 1, 11] = (zeros[:, :, 1, 11] & 0x1) | ((zeros[:, :, 2, 0] << 1) & 0x6)
+ zeros = zeros & 0x7
+ zeros = torch.cat(
+ [zeros[:, :, 0, :11], zeros[:, :, 1, 1:12], zeros[:, :, 2, 1:11]],
+ dim=2,
+ )
+
+ zeros = zeros + 1
+ zeros = zeros.reshape(self.scales.shape)
+
+ weight = self.qweight.reshape(self.qweight.shape[0] // 3, 3, 1, self.qweight.shape[1]).expand(
+ -1, -1, 12, -1
+ )
+ weight = (weight >> self.wf.unsqueeze(-1)) & 0x7
+ weight[:, 0, 10] = (weight[:, 0, 10] & 0x3) | ((weight[:, 1, 0] << 2) & 0x4)
+ weight[:, 1, 11] = (weight[:, 1, 11] & 0x1) | ((weight[:, 2, 0] << 1) & 0x6)
+ weight = weight & 0x7
+ weight = torch.cat([weight[:, 0, :11], weight[:, 1, 1:12], weight[:, 2, 1:11]], dim=1)
+ else:
+ raise NotImplementedError("Only 2,3,4,8 bits are supported.")
+
+ weight = weight.reshape(weight.shape[0] * weight.shape[1], weight.shape[2])
+ num_itr = self.g_idx.shape[0] // x.shape[-1]
+ if num_itr == 1:
+ weights = self.scales[self.g_idx.long()] * (weight - zeros[self.g_idx.long()])
+ else:
+ num_dim = self.g_idx.shape[0] // num_itr
+ weights = []
+ for i in range(num_itr):
+ scale_i = self.scales[:, i * num_dim : (i + 1) * num_dim]
+ weight_i = weight[:, i * num_dim : (i + 1) * num_dim]
+ zeros_i = zeros[:, i * num_dim : (i + 1) * num_dim]
+ g_idx_i = self.g_idx[i * num_dim : (i + 1) * num_dim]
+ weights.append(scale_i[g_idx_i.long()] * (weight_i - zeros_i[g_idx_i.long()]))
+ weights = torch.cat(weights, dim=1)
+ out = torch.matmul(x, weights)
+ out = out.to(x_dtype)
+ out = out.reshape(out_shape)
+ out = out + self.bias if self.bias is not None else out
+ return out
+
+
+__all__ = ["QuantLinear"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_cuda_old.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_cuda_old.py
new file mode 100644
index 0000000000000000000000000000000000000000..a8fe2d996de79955fefccfe232cf435c7663c3ae
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_cuda_old.py
@@ -0,0 +1,358 @@
+import math
+from logging import getLogger
+
+import numpy as np
+import torch
+import torch.nn as nn
+import transformers
+
+
+logger = getLogger(__name__)
+try:
+ import autogptq_cuda_64
+ import autogptq_cuda_256
+
+ _autogptq_cuda_available = True
+except ImportError:
+ logger.warning("CUDA extension not installed.")
+ autogptq_cuda_256 = None
+ autogptq_cuda_64 = None
+ _autogptq_cuda_available = False
+
+
+class QuantLinear(nn.Module):
+ QUANT_TYPE = "cuda-old"
+
+ def __init__(
+ self,
+ bits,
+ group_size,
+ infeatures,
+ outfeatures,
+ bias,
+ use_cuda_fp16=True,
+ kernel_switch_threshold=128,
+ trainable=False,
+ weight_dtype=torch.float16,
+ ):
+ super().__init__()
+ global _autogptq_cuda_available
+ if bits not in [2, 3, 4, 8]:
+ raise NotImplementedError("Only 2,3,4,8 bits are supported.")
+ if trainable:
+ _autogptq_cuda_available = False
+ self.infeatures = infeatures
+ self.outfeatures = outfeatures
+ self.bits = bits
+ self.group_size = group_size if group_size != -1 else infeatures
+ self.maxq = 2**self.bits - 1
+
+ self.register_buffer(
+ "qweight",
+ torch.zeros((infeatures // 32 * self.bits, outfeatures), dtype=torch.int32),
+ )
+ self.register_buffer(
+ "qzeros",
+ torch.zeros(
+ (
+ math.ceil(infeatures / self.group_size),
+ outfeatures // 32 * self.bits,
+ ),
+ dtype=torch.int32,
+ ),
+ )
+ self.register_buffer(
+ "scales",
+ torch.zeros(
+ (math.ceil(infeatures / self.group_size), outfeatures),
+ dtype=weight_dtype,
+ ),
+ )
+ self.register_buffer(
+ "g_idx",
+ torch.tensor([i // self.group_size for i in range(infeatures)], dtype=torch.int32),
+ )
+
+ if bias:
+ self.register_buffer("bias", torch.zeros((outfeatures), dtype=weight_dtype))
+ else:
+ self.bias = None
+ self.half_indim = self.infeatures // 2
+
+ self.use_cuda_fp16 = use_cuda_fp16 if bits != 8 else False
+
+ # is performed by unpacking the weights and using torch.matmul
+ if self.bits in [2, 4, 8]:
+ self.wf = torch.tensor(list(range(0, 32, self.bits)), dtype=torch.int32).unsqueeze(0)
+ elif self.bits == 3:
+ self.wf = torch.tensor(
+ [
+ [0, 3, 6, 9, 12, 15, 18, 21, 24, 27, 30, 0],
+ [0, 1, 4, 7, 10, 13, 16, 19, 22, 25, 28, 31],
+ [0, 2, 5, 8, 11, 14, 17, 20, 23, 26, 29, 0],
+ ],
+ dtype=torch.int32,
+ ).reshape(1, 3, 12)
+
+ self.kernel_switch_threshold = kernel_switch_threshold
+ self.autogptq_cuda_available = _autogptq_cuda_available
+ self.autogptq_cuda = autogptq_cuda_256
+ if infeatures % 256 != 0 or outfeatures % 256 != 0:
+ self.autogptq_cuda = autogptq_cuda_64
+ if infeatures % 64 != 0 or outfeatures % 64 != 0:
+ self.autogptq_cuda_available = False
+
+ self.trainable = trainable
+
+ def post_init(self):
+ pass
+
+ def pack(self, linear, scales, zeros, g_idx):
+ W = linear.weight.data.clone()
+ if isinstance(linear, nn.Conv2d):
+ W = W.flatten(1)
+ if isinstance(linear, transformers.pytorch_utils.Conv1D):
+ W = W.t()
+
+ scales = scales.t().contiguous()
+ zeros = zeros.t().contiguous()
+ scale_zeros = zeros * scales
+ self.scales = scales.clone().to(dtype=linear.weight.dtype)
+ if linear.bias is not None:
+ self.bias = linear.bias.clone().to(dtype=linear.weight.dtype)
+
+ intweight = []
+ for idx in range(self.infeatures):
+ g_idx = idx // self.group_size
+ intweight.append(torch.round((W[:, idx] + scale_zeros[g_idx]) / self.scales[g_idx]).to(torch.int)[:, None])
+ intweight = torch.cat(intweight, dim=1)
+ intweight = intweight.t().contiguous()
+ intweight = intweight.numpy().astype(np.uint32)
+
+ i = 0
+ row = 0
+ qweight = np.zeros((intweight.shape[0] // 32 * self.bits, intweight.shape[1]), dtype=np.uint32)
+ while row < qweight.shape[0]:
+ if self.bits in [2, 4, 8]:
+ for j in range(i, i + (32 // self.bits)):
+ qweight[row] |= intweight[j] << (self.bits * (j - i))
+ i += 32 // self.bits
+ row += 1
+ elif self.bits == 3:
+ for j in range(i, i + 10):
+ qweight[row] |= intweight[j] << (3 * (j - i))
+ i += 10
+ qweight[row] |= intweight[i] << 30
+ row += 1
+ qweight[row] |= (intweight[i] >> 2) & 1
+ i += 1
+ for j in range(i, i + 10):
+ qweight[row] |= intweight[j] << (3 * (j - i) + 1)
+ i += 10
+ qweight[row] |= intweight[i] << 31
+ row += 1
+ qweight[row] |= (intweight[i] >> 1) & 0x3
+ i += 1
+ for j in range(i, i + 10):
+ qweight[row] |= intweight[j] << (3 * (j - i) + 2)
+ i += 10
+ row += 1
+ else:
+ raise NotImplementedError("Only 2,3,4,8 bits are supported.")
+
+ qweight = qweight.astype(np.int32)
+ self.qweight = torch.from_numpy(qweight)
+
+ zeros -= 1
+ zeros = zeros.numpy().astype(np.uint32)
+ qzeros = np.zeros((zeros.shape[0], zeros.shape[1] // 32 * self.bits), dtype=np.uint32)
+ i = 0
+ col = 0
+ while col < qzeros.shape[1]:
+ if self.bits in [2, 4, 8]:
+ for j in range(i, i + (32 // self.bits)):
+ qzeros[:, col] |= zeros[:, j] << (self.bits * (j - i))
+ i += 32 // self.bits
+ col += 1
+ elif self.bits == 3:
+ for j in range(i, i + 10):
+ qzeros[:, col] |= zeros[:, j] << (3 * (j - i))
+ i += 10
+ qzeros[:, col] |= zeros[:, i] << 30
+ col += 1
+ qzeros[:, col] |= (zeros[:, i] >> 2) & 1
+ i += 1
+ for j in range(i, i + 10):
+ qzeros[:, col] |= zeros[:, j] << (3 * (j - i) + 1)
+ i += 10
+ qzeros[:, col] |= zeros[:, i] << 31
+ col += 1
+ qzeros[:, col] |= (zeros[:, i] >> 1) & 0x3
+ i += 1
+ for j in range(i, i + 10):
+ qzeros[:, col] |= zeros[:, j] << (3 * (j - i) + 2)
+ i += 10
+ col += 1
+ else:
+ raise NotImplementedError("Only 2,3,4,8 bits are supported.")
+
+ qzeros = qzeros.astype(np.int32)
+ self.qzeros = torch.from_numpy(qzeros)
+
+ def forward(self, x):
+ x_dtype = x.dtype
+ out_shape = x.shape[:-1] + (self.outfeatures,)
+ x = x.reshape(-1, x.shape[-1])
+ if (
+ x.device.type == "cuda"
+ and self.autogptq_cuda_available is True
+ and (self.kernel_switch_threshold is False or x.shape[0] < self.kernel_switch_threshold)
+ ):
+ out = torch.zeros(x.shape[0], out_shape[-1], dtype=torch.float, device=x.device)
+ if self.use_cuda_fp16:
+ if x_dtype != torch.float16:
+ logger.warning_once(
+ f"The cuda-old kernel for GPTQ with use_cuda_fp16=True requires a float16 input activation, while {x_dtype} was passed. Casting to float16.\nMake sure you loaded your model with torch_dtype=torch.float16, that the model definition does not inadvertently cast to float32, or disable AMP Autocast that may produce float32 intermediate activations in the model."
+ )
+
+ if self.bits == 2:
+ self.autogptq_cuda.vecquant2matmul_faster_old(
+ x,
+ self.qweight,
+ out,
+ self.scales.float(),
+ self.qzeros,
+ self.group_size,
+ self.half_indim,
+ )
+ elif self.bits == 3:
+ self.autogptq_cuda.vecquant3matmul_faster_old(
+ x,
+ self.qweight,
+ out,
+ self.scales.float(),
+ self.qzeros,
+ self.group_size,
+ self.half_indim,
+ )
+ elif self.bits == 4:
+ self.autogptq_cuda.vecquant4matmul_faster_old(
+ x,
+ self.qweight,
+ out,
+ self.scales.float(),
+ self.qzeros,
+ self.group_size,
+ self.half_indim,
+ )
+
+ else:
+ raise NotImplementedError("Only 2,3,4 bits are supported.")
+ else:
+ x = x.to(torch.float32) # This is required for autocast compatibility.
+ if self.bits == 2:
+ self.autogptq_cuda.vecquant2matmul_old(
+ x,
+ self.qweight,
+ out,
+ self.scales.float(),
+ self.qzeros,
+ self.group_size,
+ )
+ elif self.bits == 3:
+ self.autogptq_cuda.vecquant3matmul_old(
+ x,
+ self.qweight,
+ out,
+ self.scales.float(),
+ self.qzeros,
+ self.group_size,
+ )
+ elif self.bits == 4:
+ self.autogptq_cuda.vecquant4matmul_old(
+ x,
+ self.qweight,
+ out,
+ self.scales.float(),
+ self.qzeros,
+ self.group_size,
+ )
+ elif self.bits == 8:
+ self.autogptq_cuda.vecquant8matmul_old(
+ x,
+ self.qweight,
+ out,
+ self.scales.float(),
+ self.qzeros,
+ self.group_size,
+ )
+ else:
+ raise NotImplementedError("Only 2,3,4,8 bits are supported.")
+ else:
+ if self.wf.device != self.qzeros.device:
+ self.wf = self.wf.to(self.qzeros.device)
+
+ if self.bits in [2, 4, 8]:
+ zeros = torch.bitwise_right_shift(
+ torch.unsqueeze(self.qzeros, 2).expand(-1, -1, 32 // self.bits),
+ self.wf.unsqueeze(0),
+ ).to(torch.int16 if self.bits == 8 else torch.int8)
+
+ zeros = zeros + 1
+ zeros = torch.bitwise_and(
+ zeros, (2**self.bits) - 1
+ ) # NOTE: It appears that casting here after the `zeros = zeros + 1` is important.
+
+ zeros = zeros.reshape(-1, 1, zeros.shape[1] * zeros.shape[2])
+
+ scales = self.scales
+ scales = scales.reshape(-1, 1, scales.shape[-1])
+
+ weight = torch.bitwise_right_shift(
+ torch.unsqueeze(self.qweight, 1).expand(-1, 32 // self.bits, -1),
+ self.wf.unsqueeze(-1),
+ ).to(torch.int16 if self.bits == 8 else torch.int8)
+ weight = torch.bitwise_and(weight, (2**self.bits) - 1)
+ weight = weight.reshape(-1, self.group_size, weight.shape[2])
+ elif self.bits == 3:
+ zeros = self.qzeros.reshape(self.qzeros.shape[0], self.qzeros.shape[1] // 3, 3, 1).expand(
+ -1, -1, -1, 12
+ )
+ zeros = zeros >> self.wf.unsqueeze(0)
+ zeros[:, :, 0, 10] = (zeros[:, :, 0, 10] & 0x3) | ((zeros[:, :, 1, 0] << 2) & 0x4)
+ zeros[:, :, 1, 11] = (zeros[:, :, 1, 11] & 0x1) | ((zeros[:, :, 2, 0] << 1) & 0x6)
+ zeros = zeros & 0x7
+ zeros = torch.cat(
+ [zeros[:, :, 0, :11], zeros[:, :, 1, 1:12], zeros[:, :, 2, 1:11]],
+ dim=2,
+ )
+
+ zeros = zeros + 1
+ zeros = zeros.reshape(-1, 1, zeros.shape[1] * zeros.shape[2])
+
+ scales = self.scales
+ scales = scales.reshape(-1, 1, scales.shape[-1])
+
+ weight = self.qweight.reshape(self.qweight.shape[0] // 3, 3, 1, self.qweight.shape[1]).expand(
+ -1, -1, 12, -1
+ )
+ weight = (weight >> self.wf.unsqueeze(-1)) & 0x7
+ weight[:, 0, 10] = (weight[:, 0, 10] & 0x3) | ((weight[:, 1, 0] << 2) & 0x4)
+ weight[:, 1, 11] = (weight[:, 1, 11] & 0x1) | ((weight[:, 2, 0] << 1) & 0x6)
+ weight = weight & 0x7
+ weight = torch.cat([weight[:, 0, :11], weight[:, 1, 1:12], weight[:, 2, 1:11]], dim=1)
+ weight = weight.reshape(-1, self.group_size, weight.shape[2])
+ else:
+ raise NotImplementedError("Only 2,3,4,8 bits are supported.")
+
+ weight = scales * (weight - zeros)
+ weight = weight.reshape(weight.shape[0] * weight.shape[1], weight.shape[2])
+ out = torch.matmul(x, weight)
+ out = out.to(dtype=x_dtype).reshape(
+ out_shape
+ ) # A cast is needed here as for some reason the vecquant2matmul_faster_old still allocate a float32 output.
+ out = out + self.bias if self.bias is not None else out
+ return out
+
+
+__all__ = ["QuantLinear"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_exllama.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_exllama.py
new file mode 100644
index 0000000000000000000000000000000000000000..cfff42a7377182a57571ee92d32739e497991c53
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_exllama.py
@@ -0,0 +1,192 @@
+# Adapted from turboderp exllama: https://github.com/turboderp/exllama
+
+import math
+from logging import getLogger
+
+import numpy as np
+import torch
+import torch.nn as nn
+import transformers
+
+
+logger = getLogger(__name__)
+
+try:
+ from exllama_kernels import make_q4, q4_matmul
+except ImportError as e:
+ exllama_import_exception = e
+
+ def error_raiser_exllama(*args, **kwargs):
+ raise ValueError(
+ f"Trying to use the exllama backend, but could not import the C++/CUDA dependencies with the following error: {exllama_import_exception}"
+ )
+
+ make_q4 = error_raiser_exllama
+ q4_matmul = error_raiser_exllama
+
+# Dummy tensor to pass instead of g_idx since there is no way to pass "None" to a C++ extension
+none_tensor = torch.empty((1, 1), device="meta")
+
+
+def ext_make_q4(qweight, qzeros, scales, g_idx, device):
+ """Construct Q4Matrix, return handle"""
+ return make_q4(qweight, qzeros, scales, g_idx if g_idx is not None else none_tensor, device)
+
+
+def ext_q4_matmul(x, q4, q4_width):
+ """Matrix multiplication, returns x @ q4"""
+ outshape = x.shape[:-1] + (q4_width,)
+ x = x.view(-1, x.shape[-1])
+ output = torch.empty((x.shape[0], q4_width), dtype=torch.float16, device=x.device)
+
+ q4_matmul(x, q4, output)
+
+ return output.view(outshape)
+
+
+class QuantLinear(nn.Module):
+ QUANT_TYPE = "exllama"
+
+ """Linear layer implementation with per-group 4-bit quantization of the weights"""
+
+ def __init__(self, bits, group_size, infeatures, outfeatures, bias, trainable=False, **kwargs):
+ super().__init__()
+ if bits != 4:
+ raise ValueError(
+ f"Exllama kernel supports only bits=4, requested bits={bits}. Something is wrong in the model initialization."
+ )
+ if trainable:
+ raise NotImplementedError("Exllama kernel does not support training.")
+
+ self.padding = -outfeatures % 32
+ self.outfeatures = outfeatures + self.padding
+ outfeatures = self.outfeatures
+
+ self.infeatures = infeatures
+ self.bits = bits
+ self.group_size = group_size if group_size != -1 else infeatures
+ self.trainable = trainable
+ self.maxq = 2**self.bits - 1
+
+ assert infeatures % 32 == 0
+ assert infeatures % self.group_size == 0
+ assert outfeatures % 32 == 0
+
+ self.register_buffer(
+ "qweight",
+ torch.zeros((infeatures // 32 * self.bits, outfeatures), dtype=torch.int32),
+ )
+ self.register_buffer(
+ "qzeros",
+ torch.zeros(
+ (
+ math.ceil(infeatures / self.group_size),
+ outfeatures // 32 * self.bits,
+ ),
+ dtype=torch.int32,
+ ),
+ )
+ self.register_buffer(
+ "scales",
+ torch.zeros(
+ (math.ceil(infeatures / self.group_size), outfeatures),
+ dtype=torch.float16,
+ ),
+ )
+ self.register_buffer(
+ "g_idx",
+ torch.tensor([i // self.group_size for i in range(infeatures)], dtype=torch.int32),
+ )
+
+ if bias:
+ self.register_buffer("bias", torch.zeros((outfeatures), dtype=torch.float16))
+ else:
+ self.bias = None
+
+ def post_init(self):
+ assert self.qweight.device.type == "cuda"
+ assert self.qweight.device.index is not None
+
+ self.width = self.qweight.shape[1]
+
+ # make_q4 segfaults if g_idx is not on cpu in the act-order case. In the non act-order case, None needs to be passed for g_idx.
+ self.q4 = ext_make_q4(
+ self.qweight,
+ self.qzeros,
+ self.scales,
+ self.g_idx.to("cpu") if self._use_act_order else None,
+ self.qweight.device.index,
+ )
+
+ def pack(self, linear, scales, zeros, g_idx=None):
+ W = linear.weight.data.clone()
+ if isinstance(linear, nn.Conv2d):
+ W = W.flatten(1)
+ if isinstance(linear, transformers.pytorch_utils.Conv1D):
+ W = W.t()
+
+ self.g_idx = g_idx.clone() if g_idx is not None else self.g_idx
+
+ scales = scales.t().contiguous()
+ zeros = zeros.t().contiguous()
+ scale_zeros = zeros * scales
+ self.scales = scales.clone().half()
+ if linear.bias is not None:
+ self.bias = linear.bias.clone().half()
+
+ intweight = []
+ for idx in range(self.infeatures):
+ intweight.append(
+ torch.round((W[:, idx] + scale_zeros[self.g_idx[idx]]) / self.scales[self.g_idx[idx]]).to(torch.int)[
+ :, None
+ ]
+ )
+ intweight = torch.cat(intweight, dim=1)
+ intweight = intweight.t().contiguous()
+ intweight = intweight.numpy().astype(np.uint32)
+
+ i = 0
+ row = 0
+ qweight = np.zeros((intweight.shape[0] // 32 * self.bits, intweight.shape[1]), dtype=np.uint32)
+ while row < qweight.shape[0]:
+ if self.bits in [4]:
+ for j in range(i, i + (32 // self.bits)):
+ qweight[row] |= intweight[j] << (self.bits * (j - i))
+ i += 32 // self.bits
+ row += 1
+ else:
+ raise NotImplementedError("Only 4 bits are supported.")
+
+ qweight = qweight.astype(np.int32)
+ self.qweight = torch.from_numpy(qweight)
+
+ zeros -= 1
+ zeros = zeros.numpy().astype(np.uint32)
+ qzeros = np.zeros((zeros.shape[0], zeros.shape[1] // 32 * self.bits), dtype=np.uint32)
+ i = 0
+ col = 0
+ while col < qzeros.shape[1]:
+ if self.bits in [4]:
+ for j in range(i, i + (32 // self.bits)):
+ qzeros[:, col] |= zeros[:, j] << (self.bits * (j - i))
+ i += 32 // self.bits
+ col += 1
+ else:
+ raise NotImplementedError("Only 4 bits are supported.")
+
+ qzeros = qzeros.astype(np.int32)
+ self.qzeros = torch.from_numpy(qzeros)
+
+ def forward(self, x):
+ if x.dtype != torch.float16:
+ logger.warning_once(
+ f"The exllama kernel for GPTQ requires a float16 input activation, while {x.dtype} was passed. Casting to float16.\nMake sure you loaded your model with torch_dtype=torch.float16, that the model definition does not inadvertently cast to float32, or disable AMP Autocast that may produce float32 intermediate activations in the model."
+ )
+
+ x = x.half()
+
+ out = ext_q4_matmul(x, self.q4, self.width)
+
+ if self.bias is not None:
+ out.add_(self.bias)
+ return out
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_exllamav2.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_exllamav2.py
new file mode 100644
index 0000000000000000000000000000000000000000..6a8ad42cdd6618188ec29a663b380a27ceff32cf
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_exllamav2.py
@@ -0,0 +1,231 @@
+# Adapted from turboderp exllama: https://github.com/turboderp/exllamav2
+
+import math
+from logging import getLogger
+
+import torch
+import torch.nn as nn
+
+
+logger = getLogger(__name__)
+
+try:
+ from exllamav2_kernels import gemm_half_q_half, make_q_matrix
+except ImportError as e:
+ exllama_v2_import_exception = e
+
+ def error_raiser_exllama(*args, **kwargs):
+ raise ValueError(
+ f"Trying to use the exllama v2 backend, but could not import the C++/CUDA dependencies with the following error: {exllama_v2_import_exception}"
+ )
+
+ make_q_matrix = error_raiser_exllama
+ gemm_half_q_half = error_raiser_exllama
+
+# Dummy tensor to pass instead of g_idx since there is no way to pass "None" to a C++ extension
+none_tensor = torch.empty((1, 1), device="meta")
+
+
+def _torch_device(idx):
+ if idx == -1:
+ return "cpu"
+ return f"cuda:{idx}"
+
+
+def ext_gemm_half_q_half(x, q_handle, q4_width, force_cuda):
+ """Matrix multiplication, returns x @ q4"""
+ output_shape = x.shape[:-1] + (q4_width,)
+ x = x.view(-1, x.shape[-1])
+ output = torch.empty((x.shape[0], q4_width), dtype=torch.half, device=x.device)
+ gemm_half_q_half(x, q_handle, output, force_cuda)
+ return output.view(output_shape)
+
+
+def ext_make_q_matrix(w: dict, temp_dq, key: str = None):
+ """
+ Create Q matrix
+ """
+ # EXL2
+ # won't work as the moment because the tensors are not the same.
+ if "q_weight" in w:
+ w["q_scale_max"] /= 256
+ w["q_perm"] = w["q_perm"].short()
+ w["q_invperm"] = w["q_invperm"].short()
+ return make_q_matrix(
+ w["q_weight"],
+ w["q_perm"],
+ w["q_invperm"],
+ w["q_scale"],
+ w["q_scale_max"],
+ w["q_groups"],
+ none_tensor,
+ none_tensor,
+ none_tensor,
+ temp_dq,
+ )
+ # GPTQ
+ elif "qweight" in w:
+ if w["scales"].dtype == torch.float:
+ w["scales"] = w["scales"].half()
+
+ # GPTQ with g_idx (act_order)
+ if "g_idx" in w and not (w["g_idx"] == 0).all().item():
+ w["q_perm"] = torch.empty(
+ (w["qweight"].shape[0] * 8,),
+ dtype=torch.short,
+ device=w["qweight"].device,
+ )
+ w["q_invperm"] = torch.empty_like(w["q_perm"])
+ # make_q4 segfaults if g_idx is not on cpu in the act-order case. In the non act-order case, None needs to be passed for g_idx.
+ return make_q_matrix(
+ w["qweight"],
+ w["q_perm"],
+ w["q_invperm"],
+ none_tensor,
+ none_tensor,
+ none_tensor,
+ w["qzeros"],
+ w["scales"],
+ w["g_idx"].cpu(),
+ temp_dq,
+ )
+ # GPTQ without g_idx
+ else:
+ return make_q_matrix(
+ w["qweight"],
+ none_tensor,
+ none_tensor,
+ none_tensor,
+ none_tensor,
+ none_tensor,
+ w["qzeros"],
+ w["scales"],
+ none_tensor,
+ temp_dq,
+ )
+
+
+class QuantLinear(nn.Module):
+ QUANT_TYPE = "exllamav2"
+
+ """Linear layer implementation with per-group 4-bit quantization of the weights"""
+
+ def __init__(self, bits, group_size, infeatures, outfeatures, bias, trainable=False, **kwargs):
+ super().__init__()
+ if bits != 4:
+ raise ValueError(
+ f"Exllamav2 kernel supports only bits=4, requested bits={bits}. Something is wrong in the model initialization."
+ )
+ if trainable:
+ raise NotImplementedError("Exllamav2 kernel does not support training.")
+
+ self.q_handle = None
+ self.q_tensors = None
+
+ self.padding = -outfeatures % 32
+ self.outfeatures = outfeatures + self.padding
+ outfeatures = self.outfeatures
+
+ self.infeatures = infeatures
+ self.bits = bits
+ self.group_size = group_size if group_size != -1 else infeatures
+ self.trainable = trainable
+ self.maxq = 2**self.bits - 1
+
+ assert infeatures % 32 == 0
+ assert infeatures % self.group_size == 0
+ assert outfeatures % 32 == 0
+
+ # I need to register the tensors, otherwise, we won't be able to load them easily using transformers ...
+ self.register_buffer(
+ "qweight",
+ torch.zeros((infeatures // 32 * self.bits, outfeatures), dtype=torch.int32),
+ )
+ self.register_buffer(
+ "qzeros",
+ torch.zeros(
+ (
+ math.ceil(infeatures / self.group_size),
+ outfeatures // 32 * self.bits,
+ ),
+ dtype=torch.int32,
+ ),
+ )
+ self.register_buffer(
+ "scales",
+ torch.zeros(
+ (math.ceil(infeatures / self.group_size), outfeatures),
+ dtype=torch.float16,
+ ),
+ )
+ self.register_buffer(
+ "g_idx",
+ torch.tensor([i // self.group_size for i in range(infeatures)], dtype=torch.int32),
+ )
+
+ if bias:
+ self.register_buffer("bias", torch.zeros((outfeatures), dtype=torch.float16))
+ else:
+ self.bias = None
+
+ def post_init(self, temp_dq):
+ assert self.qweight.device.type == "cuda"
+ assert self.qweight.device.index is not None
+ self.q_tensors = {
+ "qweight": self.qweight,
+ "qzeros": self.qzeros,
+ "scales": self.scales,
+ "g_idx": self.g_idx,
+ }
+ temp_dq = temp_dq.get_scratch_slice(self.temp_dq_size())
+ self.q_handle = ext_make_q_matrix(self.q_tensors, temp_dq)
+
+ def forward(self, x, force_cuda=False):
+ if x.dtype != torch.float16:
+ logger.warning_once(
+ f"The exllama v2 kernel for GPTQ requires a float16 input activation, while {x.dtype} was passed. Casting to float16.\nMake sure you loaded your model with torch_dtype=torch.float16, that the model definition does not inadvertently cast to float32, or disable AMP Autocast that may produce float32 intermediate activations in the model."
+ )
+
+ x = x.half()
+
+ output = ext_gemm_half_q_half(x, self.q_handle, self.outfeatures, force_cuda)
+
+ if self.bias is not None:
+ output.add_(self.bias)
+ return output
+
+ def temp_dq_size(self):
+ return self.infeatures * self.outfeatures * 2 + 128
+
+ def temp_fwd_size(self, max_input_len, max_batch_size):
+ return self.outfeatures * max_input_len * max_batch_size * 4 + 128
+
+ def scratch_space_fixed(self, max_input_len=2048, max_batch_size=8):
+ return self.temp_dq_size() + self.temp_fwd_size(max_input_len, max_batch_size)
+
+
+class ExLlamaV2DeviceTensors:
+ device_idx: int
+ scratch_bytes: int
+ scratch_idx: int
+ scratch: torch.tensor = None
+
+ def __init__(self, device_idx, scratch_bytes):
+ self.device_idx = device_idx
+ self.scratch_bytes = scratch_bytes
+
+ def prepare(self):
+ self.scratch = torch.empty(
+ (self.scratch_bytes // 2,),
+ dtype=torch.half,
+ device=_torch_device(self.device_idx),
+ )
+
+ def get_scratch_slice(self, size_bytes):
+ if self.scratch is None:
+ self.prepare()
+
+ size_bytes = ((size_bytes + 127) // 128) * 128
+ size_half = size_bytes // 2
+ scratch_slice = self.scratch.narrow(0, 0, size_half)
+ return scratch_slice
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_marlin.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_marlin.py
new file mode 100644
index 0000000000000000000000000000000000000000..54a2d257662125e66d47714c0cc65ab9a49bb2b9
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_marlin.py
@@ -0,0 +1,256 @@
+# Copyright (C) Marlin.2024 Elias Frantar (elias.frantar@ist.ac.at)
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from logging import getLogger
+
+import numpy as np
+import torch
+import torch.nn as nn
+
+
+logger = getLogger(__name__)
+
+try:
+ import autogptq_marlin_cuda
+except ImportError as e:
+ marlin_import_exception = e
+
+ def error_raiser_marlin(*args, **kwargs):
+ raise ValueError(
+ f"Trying to use the marlin backend, but could not import the C++/CUDA dependencies with the following error: {marlin_import_exception}"
+ )
+
+ autogptq_marlin_cuda = error_raiser_marlin
+
+
+def mul(A, B, C, s, workspace, thread_k=-1, thread_n=-1, sms=-1, max_par=16):
+ """Marlin FP16xINT4 multiply; can be used within `torch.compile`.
+ @A: `torch.half` input matrix of shape `(m, k)` in standard row-major layout
+ @B: `torch.int` weight matrix of original shape `(k, n)` in Marlin format; see `Layer.pack()`
+ @C: `torch.half` out matrix of shape `(m, n)` in standard row-major layout
+ @s: `torch.half` scales of shape `(m / group_size, n)`
+ @workspace: `torch.int` tensor with at least `n / 128 * max_par` entries that are all zero
+ @thread_k: `k` size of a thread_tile in `B` (can usually be left as auto -1)
+ @thread_n: `n` size of a thread_tile in `B` (can usually be left as auto -1)
+ @sms: number of SMs to use for the kernel (can usually be left as auto -1)
+ @max_par: maximum number of batch 64 problems to solve in parallel for large input sizes
+ """
+ autogptq_marlin_cuda.mul(A, B, C, s, workspace, thread_k, thread_n, sms, max_par)
+
+
+# Precompute permutations for Marlin weight and scale shuffling
+
+
+def _get_perms():
+ perm = []
+ for i in range(32):
+ perm1 = []
+ col = i // 4
+ for block in [0, 1]:
+ for row in [
+ 2 * (i % 4),
+ 2 * (i % 4) + 1,
+ 2 * (i % 4 + 4),
+ 2 * (i % 4 + 4) + 1,
+ ]:
+ perm1.append(16 * row + col + 8 * block)
+ for j in range(4):
+ perm.extend([p + 256 * j for p in perm1])
+
+ perm = np.array(perm)
+ interleave = np.array([0, 2, 4, 6, 1, 3, 5, 7])
+ perm = perm.reshape((-1, 8))[:, interleave].ravel()
+ perm = torch.from_numpy(perm)
+ scale_perm = []
+ for i in range(8):
+ scale_perm.extend([i + 8 * j for j in range(8)])
+ scale_perm_single = []
+ for i in range(4):
+ scale_perm_single.extend([2 * i + j for j in [0, 1, 8, 9, 16, 17, 24, 25]])
+ return perm, scale_perm, scale_perm_single
+
+
+_perm, _scale_perm, _scale_perm_single = _get_perms()
+
+
+class QuantLinear(nn.Module):
+ QUANT_TYPE = "marlin"
+
+ def __init__(self, bits, group_size, infeatures, outfeatures, bias, trainable=False, **kwargs):
+ super().__init__()
+
+ if torch.version.hip:
+ raise ValueError("Can not use Marlin int4*fp16 kernel with AMD ROCm version of PyTorch as the kernel is not compatible. Please do not use `use_marlin=True` when using ROCm devices.")
+ if not torch.cuda.get_device_capability()[0] >= 8:
+ raise ValueError(f'Can not use Marlin int4*fp16 kernel with a device of compute capability {torch.cuda.get_device_capability()}, the minimum compute capability is 8.0 for Marlin kernel. Please do not use `use_marlin=True`, or please upgrade your GPU ("The more you buy, the more you save." - Taiwanese proverb).')
+
+ if infeatures % 128 != 0 or outfeatures % 256 != 0:
+ raise ValueError("`infeatures` must be divisible by 128 and `outfeatures` by 256.")
+ if bits not in [4]:
+ raise NotImplementedError("Only 4 bits are supported.")
+ if group_size not in [-1, 128] and group_size != infeatures:
+ raise ValueError("Only group_size -1 and 128 are supported.")
+ if infeatures % group_size != 0:
+ raise ValueError("`infeatures` must be divisible by `group_size`.")
+ if trainable:
+ raise NotImplementedError("Marlin does not support train.")
+
+ self.infeatures = infeatures
+ self.outfeatures = outfeatures
+ self.group_size = group_size if group_size != -1 else infeatures
+ self.register_buffer(
+ "B",
+ torch.empty((self.infeatures // 16, self.outfeatures * 16 // 8), dtype=torch.int),
+ )
+ self.register_buffer(
+ "s",
+ torch.empty((self.infeatures // group_size, self.outfeatures), dtype=torch.half),
+ )
+ # 128 is currently the minimum `tile_n`, hence it gives the maximum workspace size; 16 is the default `max_par`
+ self.register_buffer(
+ "workspace",
+ torch.zeros(self.outfeatures // 128 * 16, dtype=torch.int),
+ persistent=False,
+ )
+ if bias:
+ self.register_buffer("bias", torch.zeros((outfeatures), dtype=torch.half))
+ else:
+ self.bias = None
+
+ def post_init(self):
+ pass
+
+ def pack(self, linear, scales):
+ """Pack a fake-quantized linear layer into this actual Marlin representation.
+ @linear: fake-quantized `torch.nn.Linear` layer to convert (must be of type `torch.half`)
+ @scales: corresponding quantization scales of shape `(infeatures, groups)`
+ """
+ if linear.weight.dtype != torch.half:
+ raise ValueError("Only `torch.half` weights are supported.")
+ tile = 16
+ maxq = 2**4 - 1
+ s = scales.t()
+ w = linear.weight.data.t()
+ if self.group_size != self.infeatures:
+ w = w.reshape((-1, self.group_size, self.outfeatures))
+ w = w.permute(1, 0, 2)
+ w = w.reshape((self.group_size, -1))
+ s = s.reshape((1, -1))
+ w = torch.round(w / s).int()
+ w += (maxq + 1) // 2
+ w = torch.clamp(w, 0, maxq)
+ if self.group_size != self.infeatures:
+ w = w.reshape((self.group_size, -1, self.outfeatures))
+ w = w.permute(1, 0, 2)
+ w = w.reshape((self.infeatures, self.outfeatures)).contiguous()
+ s = s.reshape((-1, len(_scale_perm)))[:, _scale_perm]
+ else:
+ s = s.reshape((-1, len(_scale_perm_single)))[:, _scale_perm_single]
+ s = s.reshape((-1, self.outfeatures)).contiguous()
+ w = w.reshape((self.infeatures // tile, tile, self.outfeatures // tile, tile))
+ w = w.permute((0, 2, 1, 3))
+ w = w.reshape((self.infeatures // tile, self.outfeatures * tile))
+ res = w
+ res = res.reshape((-1, _perm.numel()))[:, _perm].reshape(res.shape)
+ q = np.zeros((res.shape[0], res.shape[1] // 8), dtype=np.uint32)
+ res = res.cpu().numpy().astype(np.uint32)
+ for i in range(8):
+ q |= res[:, i::8] << 4 * i
+ q = torch.from_numpy(q.astype(np.int32)).to(w.device)
+ self.B[:, :] = q.to(self.B.device)
+ self.s[:, :] = s.to(self.s.device)
+ if linear.bias is not None:
+ if self.bias is not None:
+ self.bias[:] = linear.bias.data.to(self.bias.device)
+ else:
+ self.bias = linear.bias.clone()
+
+ def forward(self, A):
+ A = A.half()
+ C = torch.empty(A.shape[:-1] + (self.s.shape[1],), dtype=A.dtype, device=A.device)
+ mul(
+ A.view((-1, A.shape[-1])),
+ self.B,
+ C.view((-1, C.shape[-1])),
+ self.s,
+ self.workspace,
+ )
+ C = C + self.bias if self.bias is not None else C
+ return C
+
+
+# Copied from https://github.com/IST-DASLab/marlin/pull/1
+@torch.no_grad()
+def unpack_4bit_to_32bit_signed(qweight, qzeros):
+ # Unpack 4-bit values and interpret them as signed integers
+ unpacked_weights = torch.zeros(
+ (qweight.shape[0] * 8, qweight.shape[1]),
+ dtype=torch.int8,
+ device=qweight.device,
+ requires_grad=False,
+ )
+
+ unpacked_zeros = torch.zeros(
+ (qzeros.shape[0], qzeros.shape[1] * 8),
+ dtype=torch.int8,
+ device=qzeros.device,
+ requires_grad=False,
+ )
+
+ for row in range(unpacked_weights.shape[0]):
+ i = row % 8
+ unpacked_weights[row, :] = (qweight[row // 8, :] >> (4 * i)) & 0xF
+
+ for col in range(unpacked_zeros.shape[1]):
+ i = col % 8
+ unpacked_zeros[:, col] = (qzeros[:, col // 8] >> (4 * i)) & 0xF
+
+ return unpacked_weights, unpacked_zeros + 1
+
+def unpack_qzeros(qzeros):
+ unpacked_zeros = torch.zeros(
+ (qzeros.shape[0], qzeros.shape[1] * 8),
+ dtype=torch.int8,
+ device=qzeros.device,
+ requires_grad=False,
+ )
+
+ for col in range(unpacked_zeros.shape[1]):
+ i = col % 8
+ unpacked_zeros[:, col] = (qzeros[:, col // 8] >> (4 * i)) & 0xF
+
+ return unpacked_zeros + 1
+
+
+# Copied from https://github.com/IST-DASLab/marlin/pull/1
+@torch.no_grad()
+def dequantize_weight(layer):
+ qweight, qzeros, scales = layer.qweight, layer.qzeros, layer.scales
+ unpacked_qweight, unpacked_qzeros = unpack_4bit_to_32bit_signed(qweight, qzeros)
+ group_size = unpacked_qweight.shape[0] // scales.shape[0]
+ scales = scales.repeat_interleave(group_size, dim=0)
+ unpacked_qzeros = unpacked_qzeros.repeat_interleave(group_size, dim=0)
+ unpacked_qweight = (unpacked_qweight - unpacked_qzeros) * scales
+
+ return unpacked_qweight.T, unpacked_qzeros
+
+def dequantize_qzeros(layer):
+ qzeros = layer.qzeros
+ unpacked_qzeros = unpack_qzeros(qzeros)
+ group_size = layer.group_size
+ unpacked_qzeros = unpacked_qzeros.repeat_interleave(group_size, dim=0)
+
+ return unpacked_qzeros
+
+
+__all__ = ["QuantLinear", "dequantize_weight"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_qigen.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_qigen.py
new file mode 100644
index 0000000000000000000000000000000000000000..b935fb7ed17abc160b556e73c9c438fa6f75c145
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_qigen.py
@@ -0,0 +1,377 @@
+import math
+from logging import getLogger
+
+import numpy as np
+import torch
+from gekko import GEKKO
+from torch import nn
+
+
+logger = getLogger(__name__)
+
+try:
+ import cQIGen as qinfer
+except ImportError as e:
+ exception_qinfer = e
+
+ class FakeQInfer:
+ def __getattr__(self, name):
+ raise ImportError(f"cQIGen is not installed or not correctly installed. {exception_qinfer}")
+
+
+def mem_model(N, M, T, mu, tu, bits, l1, p, gs):
+ m = GEKKO() # create GEKKO model
+ # cinfergen if bits==3:
+ # tu = tu*3
+ B = m.Const(value=bits)
+ TP = m.Const(value=T // p)
+ k = m.Var(1, integer=True, lb=1)
+ z = m.Var(1, integer=True, lb=1)
+ w = m.Var(1, integer=True, lb=1)
+ y = m.Var(1, integer=True, lb=1)
+ mb = m.Var(mu, integer=True, lb=1)
+ if gs != -1:
+ gg = m.Var(1, integer=True, lb=1)
+ tb = m.Var(tu, integer=True, lb=1, ub=int(T / p))
+ L = m.Var(integer=True, lb=0, ub=l1)
+ m.Equation(L == 32 * mb * N + B * mb * tb + 32 * tb * N)
+ m.Equation(mb * k == M)
+ if gs != -1:
+ m.Equation(gs * gg == mb)
+ # m.Equation(tb * z == T)
+ m.Equation(tb * z == TP)
+ m.Equation(mu * w == mb)
+ m.Equation(tu * y == tb)
+ # m.Equation(tb * v == tt)
+ m.Maximize(L)
+ m.options.SOLVER = 1
+ m.solver_options = [
+ "minlp_maximum_iterations 1000", # minlp iterations with integer solution
+ "minlp_max_iter_with_int_sol 10", # treat minlp as nlp
+ "minlp_as_nlp 0", # nlp sub-problem max iterations
+ "nlp_maximum_iterations 100", # 1 = depth first, 2 = breadth first
+ "minlp_branch_method 2", # maximum deviation from whole number
+ "minlp_integer_tol 0.00", # covergence tolerance
+ "minlp_gap_tol 0.01",
+ ]
+ try:
+ m.solve(disp=False)
+ except Exception:
+ try:
+ m.solver_options = [
+ "minlp_maximum_iterations 1000", # minlp iterations with integer solution
+ "minlp_max_iter_with_int_sol 10", # treat minlp as nlp
+ "minlp_as_nlp 0", # nlp sub-problem max iterations
+ "nlp_maximum_iterations 100", # 1 = depth first, 2 = breadth first
+ "minlp_branch_method 1", # maximum deviation from whole number
+ "minlp_integer_tol 0.00", # covergence tolerance
+ "minlp_gap_tol 0.01",
+ ]
+ m.solve(disp=False)
+ except Exception:
+ # mytb = T//p
+ mytb = tu
+ if gs != -1:
+ mymb = gs
+ while 32 * (mymb + gs) * N + bits * (mymb + gs) * mytb + 32 * mytb * N < l1:
+ mymb += gs
+ while M % mymb != 0:
+ mymb -= gs
+ return (int(mymb), int(mytb))
+ else:
+ mymb = mu
+ while 32 * (mymb + mu) * N + bits * (mymb + mu) * mytb + 32 * mytb * N < l1:
+ mymb += mu
+ while M % mymb != 0:
+ mymb -= mu
+ return (int(mymb), int(mytb))
+
+ return (int(mb.value[0]), int(tb.value[0]))
+
+
+params = {}
+
+
+def compute_reductions(x, gs=-1, cpp=True):
+ if cpp:
+ if len(x.shape) != 1:
+ rows, cols = x.shape
+ else:
+ rows = 1
+ cols = x.shape[0]
+ if gs == -1:
+ out = torch.zeros(rows).float().contiguous()
+ mygs = cols
+ else:
+ out = torch.zeros(rows, cols // gs).float().contiguous()
+ mygs = gs
+
+ qinfer.compute_reduction_cpp(x, out, rows, cols, mygs)
+ return out
+ if gs == -1:
+ if len(x.shape) != 1:
+ return torch.sum(x, 1)
+ else:
+ return torch.sum(x)
+ else:
+ if len(x.shape) != 1:
+ rows, cols = x.shape
+ out = torch.zeros(rows, cols // gs).float().contiguous()
+ for i in range(cols // gs):
+ out[:, i] = torch.sum(x[:, i * gs : (i + 1) * gs], 1)
+ return out
+ else:
+ cols = x.shape[0]
+ out = torch.zeros(cols // gs).float().contiguous()
+ for i in range(cols // gs):
+ out[i] = torch.sum(x[i * gs : (i + 1) * gs])
+ return out
+
+
+def process_zeros_scales(zeros, scales, bits, M):
+ if zeros.dtype != torch.float32:
+ new_zeros = torch.zeros_like(scales).float().contiguous()
+ if bits == 4:
+ qinfer.unpack_zeros4(zeros, new_zeros, new_zeros.shape[0], new_zeros.shape[1])
+ elif bits == 2:
+ qinfer.unpack_zeros2(zeros, new_zeros, new_zeros.shape[0], new_zeros.shape[1])
+ elif bits == 3:
+ logger.info("Unpacking zeros for 3 bits")
+ new_scales = scales.contiguous()
+ else:
+ if scales.shape[1] != M:
+ new_scales = scales.transpose(0, 1).contiguous()
+ else:
+ new_scales = scales.contiguous()
+ if zeros.shape[1] != M:
+ new_zeros = zeros.transpose(0, 1).contiguous()
+ else:
+ new_zeros = zeros.contiguous()
+
+ return new_zeros, new_scales
+
+
+class QuantLinear(nn.Module):
+ QUANT_TYPE = "qigen"
+
+ def __init__(
+ self,
+ bits,
+ group_size,
+ infeatures,
+ outfeatures,
+ bias=None,
+ trainable=False,
+ hint=1,
+ p=8,
+ l1=2**18,
+ ):
+ super().__init__()
+ if bits not in [2, 4]:
+ raise NotImplementedError("Only 2,4 bits are supported.")
+ if trainable:
+ raise NotImplementedError("Qigen kernel does not support training.")
+ self.bits = bits
+
+ self.infeatures = infeatures
+ self.outfeatures = outfeatures
+
+ n = hint
+ m = self.infeatures
+ t = self.outfeatures
+
+ # registers for now are fixed
+ if bits == 3:
+ packed = 32
+ mu = 32
+ tu = 32
+ else:
+ packed = 32 // bits
+ mu = 16
+ tu = 32
+
+ global params
+ if (m, t) in params:
+ mb = params[(m, t)][0]
+ tb = params[(m, t)][1]
+ else:
+ mb, tb = mem_model(n, m, t, mu, tu, bits, l1, p, group_size)
+ params[(m, t)] = (mb, tb)
+
+ split = np.ones(p)
+ split = split * tb
+ while np.sum(split) < t:
+ split = split + tb
+
+ idx = p - 1
+ while np.sum(split) > t:
+ split[idx] = split[idx] - tb
+ idx = idx - 1
+
+ assert np.sum(split) == t
+
+ split = split.astype(int)
+ self.tt = int(split[0])
+
+ if split[0] == split[-1]:
+ self.cutoff = int(p + 1)
+ else:
+ self.cutoff = int(idx + 1)
+
+ self.mb = mb # // packed
+ self.tb = tb
+
+ self.group_size = group_size
+
+ self.register_buffer("bias", torch.zeros(self.outfeatures))
+ self.register_buffer(
+ "zeros",
+ torch.zeros(
+ (math.ceil(infeatures / self.group_size), outfeatures),
+ dtype=torch.float32,
+ ),
+ )
+ self.register_buffer(
+ "scales",
+ torch.zeros(
+ (math.ceil(infeatures / self.group_size), outfeatures),
+ dtype=torch.float32,
+ ),
+ )
+ if bits == 4:
+ self.register_buffer(
+ "qweight",
+ torch.zeros(int(self.infeatures // packed * self.outfeatures)).int().contiguous(),
+ )
+ elif bits == 3:
+ self.register_buffer(
+ "qweight",
+ torch.zeros(int(self.infeatures // packed * 3 * self.outfeatures)).int().contiguous(),
+ )
+ elif bits == 2:
+ self.register_buffer(
+ "qweight",
+ torch.zeros(int(self.infeatures // packed * self.outfeatures)).int().contiguous(),
+ )
+
+ def forward(self, x):
+ out_shape = x.shape[:-1] + (self.outfeatures,)
+ x = x.reshape((-1, x.shape[-1])).to(torch.float32)
+ B = x.shape[0]
+ new_x = x.T.contiguous()
+ out = torch.zeros((B, self.outfeatures), dtype=torch.float32)
+ sums = compute_reductions(x, gs=self.group_size, cpp=True).contiguous()
+ if self.group_size == -1:
+ if self.bits == 4:
+ qinfer.forward4(
+ new_x,
+ self.qweight,
+ out,
+ self.bias,
+ self.scales,
+ self.zeros,
+ sums,
+ B,
+ self.infeatures,
+ self.outfeatures,
+ B,
+ self.mb,
+ self.tb,
+ self.tt,
+ self.cutoff,
+ )
+ elif self.bits == 2:
+ qinfer.forward2(
+ new_x,
+ self.qweight,
+ out,
+ self.bias,
+ self.scales,
+ self.zeros,
+ sums,
+ B,
+ self.infeatures,
+ self.outfeatures,
+ B,
+ self.mb,
+ self.tb,
+ self.tt,
+ self.cutoff,
+ )
+ elif self.bits == 3:
+ qinfer.forward3(
+ new_x,
+ self.qweight,
+ out,
+ self.bias,
+ self.scales,
+ self.zeros,
+ sums,
+ B,
+ self.infeatures,
+ self.outfeatures,
+ B,
+ self.mb,
+ self.tb,
+ self.tt,
+ self.cutoff,
+ )
+ else:
+ if self.bits == 4:
+ qinfer.forward_gs4(
+ new_x,
+ self.qweight,
+ out,
+ self.bias,
+ self.scales,
+ self.zeros,
+ sums,
+ B,
+ self.infeatures,
+ self.outfeatures,
+ B,
+ self.mb,
+ self.tb,
+ self.tt,
+ self.group_size,
+ self.cutoff,
+ )
+ elif self.bits == 2:
+ qinfer.forward_gs2(
+ new_x,
+ self.qweight,
+ out,
+ self.bias,
+ self.scales,
+ self.zeros,
+ sums,
+ B,
+ self.infeatures,
+ self.outfeatures,
+ B,
+ self.mb,
+ self.tb,
+ self.tt,
+ self.group_size,
+ self.cutoff,
+ )
+ elif self.bits == 3:
+ qinfer.forward_gs3(
+ new_x,
+ self.qweight,
+ out,
+ self.bias,
+ self.scales,
+ self.zeros,
+ sums,
+ B,
+ self.infeatures,
+ self.outfeatures,
+ B,
+ self.mb,
+ self.tb,
+ self.tt,
+ self.group_size,
+ self.cutoff,
+ )
+ return out.reshape(out_shape)
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_triton.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_triton.py
new file mode 100644
index 0000000000000000000000000000000000000000..93bd0f268465c9f0edce23ac6f5103c44e38fd6e
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_triton.py
@@ -0,0 +1,218 @@
+import math
+from logging import getLogger
+
+import numpy as np
+import torch
+import torch.nn as nn
+import transformers
+
+from ..triton_utils.mixin import TritonModuleMixin
+
+
+logger = getLogger(__name__)
+
+try:
+ from ..triton_utils.kernels import (
+ QuantLinearFunction,
+ QuantLinearInferenceOnlyFunction,
+ quant_matmul_248,
+ quant_matmul_inference_only_248,
+ transpose_quant_matmul_248,
+ )
+except ImportError as e:
+ triton_import_exception = e
+
+ def error_raiser_triton(*args, **kwargs):
+ raise ValueError(
+ f"Trying to use the triton backend, but could not import triton dependencies with the following error: {triton_import_exception}"
+ )
+
+ class FakeTriton:
+ def __getattr__(self, name):
+ raise ImportError(
+ f"Trying to use the triton backend, but could not import triton dependencies with the following error: {triton_import_exception}"
+ )
+
+ quant_matmul_248 = error_raiser_triton
+ transpose_quant_matmul_248 = error_raiser_triton
+ quant_matmul_inference_only_248 = error_raiser_triton
+ QuantLinearFunction = FakeTriton
+ QuantLinearInferenceOnlyFunction = FakeTriton
+
+
+class QuantLinear(nn.Module, TritonModuleMixin):
+ QUANT_TYPE = "triton"
+
+ def __init__(self, bits, group_size, infeatures, outfeatures, bias, trainable=False, **kwargs):
+ super().__init__()
+ if bits not in [2, 4, 8]:
+ raise NotImplementedError("Only 2,4,8 bits are supported.")
+ if infeatures % 32 != 0 or outfeatures % 32 != 0:
+ raise NotImplementedError("in_feature and out_feature must be divisible by 32.")
+ self.infeatures = infeatures
+ self.outfeatures = outfeatures
+ self.bits = bits
+ self.group_size = group_size if group_size != -1 else infeatures
+ self.maxq = 2**self.bits - 1
+
+ self.register_buffer(
+ "qweight",
+ torch.zeros((infeatures // 32 * self.bits, outfeatures), dtype=torch.int32),
+ )
+ self.register_buffer(
+ "qzeros",
+ torch.zeros(
+ (
+ math.ceil(infeatures / self.group_size),
+ outfeatures // 32 * self.bits,
+ ),
+ dtype=torch.int32,
+ ),
+ )
+ self.register_buffer(
+ "scales",
+ torch.zeros(
+ (math.ceil(infeatures / self.group_size), outfeatures),
+ dtype=torch.float16,
+ ),
+ )
+ self.register_buffer(
+ "g_idx",
+ torch.tensor([i // self.group_size for i in range(infeatures)], dtype=torch.int32),
+ )
+ if bias:
+ self.register_buffer("bias", torch.zeros((outfeatures), dtype=torch.float16))
+ else:
+ self.bias = None
+
+ self.trainable = trainable
+
+ def post_init(self):
+ pass
+
+ def pack(self, linear, scales, zeros, g_idx=None):
+ W = linear.weight.data.clone()
+ if isinstance(linear, nn.Conv2d):
+ W = W.flatten(1)
+ if isinstance(linear, transformers.pytorch_utils.Conv1D):
+ W = W.t()
+
+ self.g_idx = g_idx.clone() if g_idx is not None else self.g_idx
+
+ scales = scales.t().contiguous()
+ zeros = zeros.t().contiguous()
+ scale_zeros = zeros * scales
+ self.scales = scales.clone().half()
+ if linear.bias is not None:
+ self.bias = linear.bias.clone().half()
+
+ intweight = []
+ for idx in range(self.infeatures):
+ intweight.append(
+ torch.round((W[:, idx] + scale_zeros[self.g_idx[idx]]) / self.scales[self.g_idx[idx]]).to(torch.int)[
+ :, None
+ ]
+ )
+ intweight = torch.cat(intweight, dim=1)
+ intweight = intweight.t().contiguous()
+ intweight = intweight.numpy().astype(np.uint32)
+
+ i = 0
+ row = 0
+ qweight = np.zeros((intweight.shape[0] // 32 * self.bits, intweight.shape[1]), dtype=np.uint32)
+ while row < qweight.shape[0]:
+ if self.bits in [2, 4, 8]:
+ for j in range(i, i + (32 // self.bits)):
+ qweight[row] |= intweight[j] << (self.bits * (j - i))
+ i += 32 // self.bits
+ row += 1
+ else:
+ raise NotImplementedError("Only 2,4,8 bits are supported.")
+
+ qweight = qweight.astype(np.int32)
+ self.qweight = torch.from_numpy(qweight)
+
+ zeros -= 1
+ zeros = zeros.numpy().astype(np.uint32)
+ qzeros = np.zeros((zeros.shape[0], zeros.shape[1] // 32 * self.bits), dtype=np.uint32)
+ i = 0
+ col = 0
+ while col < qzeros.shape[1]:
+ if self.bits in [2, 4, 8]:
+ for j in range(i, i + (32 // self.bits)):
+ qzeros[:, col] |= zeros[:, j] << (self.bits * (j - i))
+ i += 32 // self.bits
+ col += 1
+ else:
+ raise NotImplementedError("Only 2,4,8 bits are supported.")
+
+ qzeros = qzeros.astype(np.int32)
+ self.qzeros = torch.from_numpy(qzeros)
+
+ def forward(self, x):
+ out_shape = x.shape[:-1] + (self.outfeatures,)
+ quant_linear_fn = QuantLinearFunction if self.trainable else QuantLinearInferenceOnlyFunction
+ out = quant_linear_fn.apply(
+ x.reshape(-1, x.shape[-1]),
+ self.qweight,
+ self.scales,
+ self.qzeros,
+ self.g_idx,
+ self.bits,
+ self.maxq,
+ )
+ out = out.half().reshape(out_shape)
+ out = out + self.bias if self.bias is not None else out
+ return out
+
+ @classmethod
+ def warmup(cls, model, transpose=False, seqlen=2048):
+ """
+ Pre-tunes the quantized kernel
+ """
+ from tqdm import tqdm
+
+ kn_values = {}
+
+ for _, m in model.named_modules():
+ if not isinstance(m, cls):
+ continue
+
+ k = m.infeatures
+ n = m.outfeatures
+
+ if (k, n) not in kn_values:
+ kn_values[(k, n)] = (
+ m.qweight,
+ m.scales,
+ m.qzeros,
+ m.g_idx,
+ m.bits,
+ m.maxq,
+ )
+
+ logger.info(f"Found {len(kn_values)} unique KN Linear values.")
+ logger.info("Warming up autotune cache ...")
+ with torch.no_grad():
+ for m in tqdm(range(0, math.ceil(math.log2(seqlen)) + 1)):
+ m = 2**m
+ for (k, n), (
+ qweight,
+ scales,
+ qzeros,
+ g_idx,
+ bits,
+ maxq,
+ ) in kn_values.items():
+ if transpose:
+ a = torch.randn(m, k, dtype=torch.float16, device=model.device)
+ quant_matmul_248(a, qweight, scales, qzeros, g_idx, bits, maxq)
+ a = torch.randn(m, n, dtype=torch.float16, device=model.device)
+ transpose_quant_matmul_248(a, qweight, scales, qzeros, g_idx, bits, maxq)
+ else:
+ a = torch.randn(m, k, dtype=torch.float16, device=model.device)
+ quant_matmul_inference_only_248(a, qweight, scales, qzeros, g_idx, bits, maxq)
+ del kn_values
+
+
+__all__ = ["QuantLinear"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_tritonv2.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_tritonv2.py
new file mode 100644
index 0000000000000000000000000000000000000000..82e948ac589ccb55d8ac9ca339893714432d3b45
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/qlinear/qlinear_tritonv2.py
@@ -0,0 +1,226 @@
+import math
+from logging import getLogger
+
+import numpy as np
+import torch
+import torch.nn as nn
+import transformers
+
+from ..triton_utils.mixin import TritonModuleMixin
+
+
+logger = getLogger(__name__)
+
+try:
+ from ..triton_utils.dequant import QuantLinearFunction, quant_matmul_248
+except ImportError as e:
+ triton_import_exception = e
+
+ def error_raiser_triton(*args, **kwargs):
+ raise ValueError(
+ f"Trying to use the triton backend, but could not import triton dependencies with the following error: {triton_import_exception}"
+ )
+
+ class FakeTriton:
+ def __getattr__(self, name):
+ raise ImportError(
+ f"Trying to use the triton backend, but could not import triton dependencies with the following error: {triton_import_exception}"
+ )
+
+ quant_matmul_248 = error_raiser_triton
+ QuantLinearFunction = FakeTriton
+ QuantLinearInferenceOnlyFunction = FakeTriton
+
+
+class QuantLinear(nn.Module, TritonModuleMixin):
+ """
+ Triton v2 quantized linear layer.
+
+ Calls dequant kernel (see triton_utils/dequant) to dequantize the weights then uses
+ torch.matmul to compute the output whereas original `triton` quantized linear layer fused
+ dequant and matmul into single kernel.add()
+ """
+
+ QUANT_TYPE = "tritonv2"
+
+ def __init__(
+ self, bits, group_size, infeatures, outfeatures, bias, trainable=False, **kwargs
+ ):
+ super().__init__()
+ if bits not in [2, 4, 8]:
+ raise NotImplementedError("Only 2,4,8 bits are supported.")
+ if infeatures % 32 != 0 or outfeatures % 32 != 0:
+ raise NotImplementedError(
+ "in_feature and out_feature must be divisible by 32."
+ )
+ self.infeatures = infeatures
+ self.outfeatures = outfeatures
+ self.bits = bits
+ self.group_size = group_size if group_size != -1 else infeatures
+ self.maxq = 2**self.bits - 1
+
+ self.register_buffer(
+ "qweight",
+ torch.zeros((infeatures // 32 * self.bits, outfeatures), dtype=torch.int32),
+ )
+ self.register_buffer(
+ "qzeros",
+ torch.zeros(
+ (
+ math.ceil(infeatures / self.group_size),
+ outfeatures // 32 * self.bits,
+ ),
+ dtype=torch.int32,
+ ),
+ )
+ self.register_buffer(
+ "scales",
+ torch.zeros(
+ (math.ceil(infeatures / self.group_size), outfeatures),
+ dtype=torch.float16,
+ ),
+ )
+ self.register_buffer(
+ "g_idx",
+ torch.tensor(
+ [i // self.group_size for i in range(infeatures)], dtype=torch.int32
+ ),
+ )
+ if bias:
+ self.register_buffer(
+ "bias", torch.zeros((outfeatures), dtype=torch.float16)
+ )
+ else:
+ self.bias = None
+
+ self.trainable = trainable
+
+ def post_init(self):
+ pass
+
+ def pack(self, linear, scales, zeros, g_idx=None):
+ W = linear.weight.data.clone()
+ if isinstance(linear, nn.Conv2d):
+ W = W.flatten(1)
+ if isinstance(linear, transformers.pytorch_utils.Conv1D):
+ W = W.t()
+
+ self.g_idx = g_idx.clone() if g_idx is not None else self.g_idx
+
+ scales = scales.t().contiguous()
+ zeros = zeros.t().contiguous()
+ scale_zeros = zeros * scales
+ self.scales = scales.clone().half()
+ if linear.bias is not None:
+ self.bias = linear.bias.clone().half()
+
+ intweight = []
+ for idx in range(self.infeatures):
+ intweight.append(
+ torch.round(
+ (W[:, idx] + scale_zeros[self.g_idx[idx]])
+ / self.scales[self.g_idx[idx]]
+ ).to(torch.int)[:, None]
+ )
+ intweight = torch.cat(intweight, dim=1)
+ intweight = intweight.t().contiguous()
+ intweight = intweight.numpy().astype(np.uint32)
+
+ i = 0
+ row = 0
+ qweight = np.zeros(
+ (intweight.shape[0] // 32 * self.bits, intweight.shape[1]), dtype=np.uint32
+ )
+ while row < qweight.shape[0]:
+ if self.bits in [2, 4, 8]:
+ for j in range(i, i + (32 // self.bits)):
+ qweight[row] |= intweight[j] << (self.bits * (j - i))
+ i += 32 // self.bits
+ row += 1
+ else:
+ raise NotImplementedError("Only 2,4,8 bits are supported.")
+
+ qweight = qweight.astype(np.int32)
+ self.qweight = torch.from_numpy(qweight)
+
+ zeros -= 1
+ zeros = zeros.numpy().astype(np.uint32)
+ qzeros = np.zeros(
+ (zeros.shape[0], zeros.shape[1] // 32 * self.bits), dtype=np.uint32
+ )
+ i = 0
+ col = 0
+ while col < qzeros.shape[1]:
+ if self.bits in [2, 4, 8]:
+ for j in range(i, i + (32 // self.bits)):
+ qzeros[:, col] |= zeros[:, j] << (self.bits * (j - i))
+ i += 32 // self.bits
+ col += 1
+ else:
+ raise NotImplementedError("Only 2,4,8 bits are supported.")
+
+ qzeros = qzeros.astype(np.int32)
+ self.qzeros = torch.from_numpy(qzeros)
+
+ def forward(self, x):
+ out_shape = x.shape[:-1] + (self.outfeatures,)
+ quant_linear_fn = QuantLinearFunction
+
+ out = quant_linear_fn.apply(
+ x.reshape(-1, x.shape[-1]),
+ self.qweight,
+ self.scales,
+ self.qzeros,
+ self.g_idx,
+ self.bits,
+ self.maxq,
+ )
+ out = out.half().reshape(out_shape)
+ out = out + self.bias if self.bias is not None else out
+ return out
+
+ @classmethod
+ def warmup(cls, model, transpose=False, seqlen=2048):
+ """
+ Pre-tunes the quantized kernel
+ """
+ from tqdm import tqdm
+
+ kn_values = {}
+
+ for _, m in model.named_modules():
+ if not isinstance(m, cls):
+ continue
+
+ k = m.infeatures
+ n = m.outfeatures
+
+ if (k, n) not in kn_values:
+ kn_values[(k, n)] = (
+ m.qweight,
+ m.scales,
+ m.qzeros,
+ m.g_idx,
+ m.bits,
+ m.maxq,
+ )
+
+ logger.info(f"Found {len(kn_values)} unique KN Linear values.")
+ logger.info("Warming up autotune cache ...")
+ with torch.no_grad():
+ for m in tqdm(range(0, math.ceil(math.log2(seqlen)) + 1)):
+ m = 2**m
+ for (k, n), (
+ qweight,
+ scales,
+ qzeros,
+ g_idx,
+ bits,
+ maxq,
+ ) in kn_values.items():
+ a = torch.randn(m, k, dtype=torch.float16, device=model.device)
+ quant_matmul_248(a, qweight, scales, qzeros, g_idx, bits, maxq)
+ del kn_values
+
+
+__all__ = ["QuantLinear"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/triton_utils/__init__.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/triton_utils/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/triton_utils/custom_autotune.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/triton_utils/custom_autotune.py
new file mode 100644
index 0000000000000000000000000000000000000000..ff2d14a3cd59324e0e6a0d3babba1b20de776852
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/triton_utils/custom_autotune.py
@@ -0,0 +1,219 @@
+import builtins
+import math
+import time
+from typing import Dict
+
+import triton
+
+
+# code based https://github.com/fpgaminer/GPTQ-triton
+"""
+Mostly the same as the autotuner in Triton, but with a few changes like using 40 runs instead of 100.
+"""
+
+
+class CustomizedTritonAutoTuner(triton.KernelInterface):
+ def __init__(
+ self,
+ fn,
+ arg_names,
+ configs,
+ key,
+ reset_to_zero,
+ prune_configs_by: Dict = None,
+ nearest_power_of_two: bool = False,
+ ):
+ if not configs:
+ self.configs = [triton.Config({}, num_warps=4, num_stages=2)]
+ else:
+ self.configs = configs
+ self.key_idx = [arg_names.index(k) for k in key]
+ self.nearest_power_of_two = nearest_power_of_two
+ self.cache = {}
+ # hook to reset all required tensor to zeros before relaunching a kernel
+ self.hook = lambda args: 0
+ if reset_to_zero is not None:
+ self.reset_idx = [arg_names.index(k) for k in reset_to_zero]
+
+ def _hook(args):
+ for i in self.reset_idx:
+ args[i].zero_()
+
+ self.hook = _hook
+ self.arg_names = arg_names
+ # prune configs
+ if prune_configs_by:
+ perf_model, top_k = (
+ prune_configs_by["perf_model"],
+ prune_configs_by["top_k"],
+ )
+ if "early_config_prune" in prune_configs_by:
+ early_config_prune = prune_configs_by["early_config_prune"]
+ else:
+ perf_model, top_k, early_config_prune = None, None, None
+ self.perf_model, self.configs_top_k = perf_model, top_k
+ self.early_config_prune = early_config_prune
+ self.fn = fn
+
+ def _bench(self, *args, config, **meta):
+ # check for conflicts, i.e. meta-parameters both provided
+ # as kwargs and by the autotuner
+ conflicts = meta.keys() & config.kwargs.keys()
+ if conflicts:
+ raise ValueError(
+ f"Conflicting meta-parameters: {', '.join(conflicts)}."
+ " Make sure that you don't re-define auto-tuned symbols."
+ )
+ # augment meta-parameters with tunable ones
+ current = dict(meta, **config.kwargs)
+
+ def kernel_call():
+ if config.pre_hook:
+ config.pre_hook(self.nargs)
+ self.hook(args)
+ self.fn.run(
+ *args,
+ num_warps=config.num_warps,
+ num_stages=config.num_stages,
+ **current,
+ )
+
+ try:
+ # In testings using only 40 reps seems to be close enough and it appears to be what PyTorch uses
+ # PyTorch also sets fast_flush to True, but I didn't see any speedup so I'll leave the default
+ return triton.testing.do_bench(kernel_call, quantiles=(0.5, 0.2, 0.8), rep=40)
+ except triton.OutOfResources:
+ return (float("inf"), float("inf"), float("inf"))
+
+ def run(self, *args, **kwargs):
+ self.nargs = dict(zip(self.arg_names, args))
+ if len(self.configs) > 1:
+ key = tuple(args[i] for i in self.key_idx)
+
+ # This reduces the amount of autotuning by rounding the keys to the nearest power of two
+ # In my testing this gives decent results, and greatly reduces the amount of tuning required
+ if self.nearest_power_of_two:
+ key = tuple([2 ** int(math.log2(x) + 0.5) for x in key])
+
+ if key not in self.cache:
+ # prune configs
+ pruned_configs = self.prune_configs(kwargs)
+ bench_start = time.time()
+ timings = {config: self._bench(*args, config=config, **kwargs) for config in pruned_configs}
+ bench_end = time.time()
+ self.bench_time = bench_end - bench_start
+ self.cache[key] = builtins.min(timings, key=timings.get)
+ self.hook(args)
+ self.configs_timings = timings
+ config = self.cache[key]
+ else:
+ config = self.configs[0]
+ self.best_config = config
+ if config.pre_hook is not None:
+ config.pre_hook(self.nargs)
+ return self.fn.run(
+ *args,
+ num_warps=config.num_warps,
+ num_stages=config.num_stages,
+ **kwargs,
+ **config.kwargs,
+ )
+
+ def prune_configs(self, kwargs):
+ pruned_configs = self.configs
+ if self.early_config_prune:
+ pruned_configs = self.early_config_prune(self.configs, self.nargs)
+ if self.perf_model:
+ top_k = self.configs_top_k
+ if isinstance(top_k, float) and top_k <= 1.0:
+ top_k = int(len(self.configs) * top_k)
+ if len(pruned_configs) > top_k:
+ est_timing = {
+ config: self.perf_model(
+ **self.nargs,
+ **kwargs,
+ **config.kwargs,
+ num_stages=config.num_stages,
+ num_warps=config.num_warps,
+ )
+ for config in pruned_configs
+ }
+ pruned_configs = sorted(est_timing.keys(), key=lambda x: est_timing[x])[:top_k]
+ return pruned_configs
+
+ def warmup(self, *args, **kwargs):
+ self.nargs = dict(zip(self.arg_names, args))
+ for config in self.prune_configs(kwargs):
+ self.fn.warmup(
+ *args,
+ num_warps=config.num_warps,
+ num_stages=config.num_stages,
+ **kwargs,
+ **config.kwargs,
+ )
+ self.nargs = None
+
+
+def autotune(configs, key, prune_configs_by=None, reset_to_zero=None, nearest_power_of_two=False):
+ def decorator(fn):
+ return CustomizedTritonAutoTuner(
+ fn,
+ fn.arg_names,
+ configs,
+ key,
+ reset_to_zero,
+ prune_configs_by,
+ nearest_power_of_two,
+ )
+
+ return decorator
+
+
+def matmul248_kernel_config_pruner(configs, nargs):
+ """
+ The main purpose of this function is to shrink BLOCK_SIZE_* when the corresponding dimension is smaller.
+ """
+ m = max(2 ** int(math.ceil(math.log2(nargs["M"]))), 16)
+ n = max(2 ** int(math.ceil(math.log2(nargs["N"]))), 16)
+ k = max(2 ** int(math.ceil(math.log2(nargs["K"]))), 16)
+
+ used = set()
+ for config in configs:
+ block_size_m = min(m, config.kwargs["BLOCK_SIZE_M"])
+ block_size_n = min(n, config.kwargs["BLOCK_SIZE_N"])
+ block_size_k = min(k, config.kwargs["BLOCK_SIZE_K"])
+ group_size_m = config.kwargs["GROUP_SIZE_M"]
+
+ if (
+ block_size_m,
+ block_size_n,
+ block_size_k,
+ group_size_m,
+ config.num_stages,
+ config.num_warps,
+ ) in used:
+ continue
+
+ used.add(
+ (
+ block_size_m,
+ block_size_n,
+ block_size_k,
+ group_size_m,
+ config.num_stages,
+ config.num_warps,
+ )
+ )
+ yield triton.Config(
+ {
+ "BLOCK_SIZE_M": block_size_m,
+ "BLOCK_SIZE_N": block_size_n,
+ "BLOCK_SIZE_K": block_size_k,
+ "GROUP_SIZE_M": group_size_m,
+ },
+ num_stages=config.num_stages,
+ num_warps=config.num_warps,
+ )
+
+
+__all__ = ["autotune"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/triton_utils/dequant.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/triton_utils/dequant.py
new file mode 100644
index 0000000000000000000000000000000000000000..ea7375a737f5789ba26a8d17dedb365d045ecd87
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/triton_utils/dequant.py
@@ -0,0 +1,145 @@
+import itertools
+
+import torch
+import triton
+import triton.language as tl
+from torch.cuda.amp import custom_bwd, custom_fwd
+
+
+def make_dequant_configs(block_sizes, num_warps):
+ configs = []
+ for bs, ws in itertools.product(block_sizes, num_warps):
+ configs.append(triton.Config({"X_BLOCK": bs}, num_warps=ws))
+ return configs
+
+
+DEFAULT_DEQUANT_CONFIGS = make_dequant_configs([128, 256, 512, 1024], [4, 8])
+
+
+@triton.autotune(DEFAULT_DEQUANT_CONFIGS, key=["numels"])
+@triton.jit
+def dequant_kernel_248(
+ g_idx_ptr,
+ scales_ptr,
+ qweight_ptr,
+ qzeros_ptr,
+ out_ptr,
+ numels,
+ maxq: tl.constexpr,
+ bits: tl.constexpr,
+ outfeatures: tl.constexpr,
+ num_groups: tl.constexpr,
+ X_BLOCK: tl.constexpr,
+):
+ # Block indexing
+ xoffset = tl.program_id(0) * X_BLOCK
+ x_index = xoffset + tl.arange(0, X_BLOCK)
+ xmask = x_index < numels
+ row_idx = x_index // outfeatures
+ col_idx = x_index % outfeatures
+
+ elements_per_feature: tl.constexpr = 32 // bits
+
+ # Load parameters
+ g_idx = tl.load(g_idx_ptr + (row_idx), None, eviction_policy="evict_last")
+ qweights = tl.load(
+ qweight_ptr + (col_idx + (outfeatures * (row_idx // elements_per_feature))),
+ None,
+ )
+
+ wf_weights = (row_idx % elements_per_feature) * bits
+
+ wf_zeros = (col_idx % elements_per_feature) * bits
+
+ tmp1 = g_idx + num_groups
+ tmp2 = g_idx < 0
+ tl.device_assert(g_idx >= 0, "index out of bounds: 0 <= tmp0 < 0")
+ groups = tl.where(tmp2, tmp1, g_idx) # tmp3 are g_idx
+
+ scales = tl.load(scales_ptr + (col_idx + (outfeatures * groups)), None).to(
+ tl.float32
+ )
+
+ # Unpack weights
+ weights = qweights >> wf_weights # bit shift qweight
+
+ weights = weights & maxq
+
+ # Unpack zeros
+ qzero_ncols: tl.constexpr = outfeatures // elements_per_feature
+ qzeros = tl.load(
+ qzeros_ptr + ((qzero_ncols * groups) + (col_idx // elements_per_feature)),
+ None,
+ eviction_policy="evict_last",
+ )
+ zeros = qzeros >> wf_zeros
+ zeros = zeros & maxq
+
+ # Dequantize
+ zeros = zeros + 1
+ weights = weights - zeros
+ weights = weights.to(tl.float32)
+ weights = scales * weights
+
+ tl.store(out_ptr + (x_index), weights, mask=xmask)
+
+
+def dequant248(qweight, scales, qzeros, g_idx, bits, maxq=None):
+ """
+ Launcher for triton dequant kernel. Only valid for bits = 2, 4, 8
+ """
+
+ num_groups = scales.shape[0]
+ outfeatures = scales.shape[1]
+ infeatures = g_idx.shape[0]
+
+ out = torch.empty((infeatures, outfeatures), device="cuda", dtype=torch.float16)
+ numels = out.numel()
+ maxq = 2**bits - 1 if maxq is None else maxq
+ grid = lambda meta: (triton.cdiv(numels, meta["X_BLOCK"]),) # noqa: E731
+
+ dequant_kernel_248[grid](
+ g_idx,
+ scales,
+ qweight,
+ qzeros,
+ out,
+ numels,
+ maxq=maxq,
+ bits=bits,
+ outfeatures=outfeatures,
+ num_groups=num_groups,
+ )
+ return out
+
+
+def quant_matmul_248(
+ input, qweight, scales, qzeros, g_idx, bits, maxq=None, transpose=False
+):
+ W = dequant248(qweight, scales, qzeros, g_idx, bits, maxq=maxq)
+ if transpose:
+ return input @ W.t()
+ return input @ W
+
+
+class QuantLinearFunction(torch.autograd.Function):
+ @staticmethod
+ @custom_fwd
+ def forward(ctx, input, qweight, scales, qzeros, g_idx, bits, maxq):
+ output = quant_matmul_248(input, qweight, scales, qzeros, g_idx, bits, maxq)
+ ctx.save_for_backward(qweight, scales, qzeros, g_idx)
+ ctx.bits, ctx.maxq = bits, maxq
+ return output
+
+ @staticmethod
+ @custom_bwd
+ def backward(ctx, grad_output):
+ qweight, scales, qzeros, g_idx = ctx.saved_tensors
+ bits, maxq = ctx.bits, ctx.maxq
+ grad_input = None
+
+ if ctx.needs_input_grad[0]:
+ grad_input = quant_matmul_248(
+ grad_output, qweight, scales, qzeros, g_idx, bits, maxq, transpose=True
+ )
+ return grad_input, None, None, None, None, None, None
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/triton_utils/kernels.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/triton_utils/kernels.py
new file mode 100644
index 0000000000000000000000000000000000000000..30c6caa88d8c6d04736d2e714da349f6a5af9ce6
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/triton_utils/kernels.py
@@ -0,0 +1,464 @@
+from logging import getLogger
+
+import torch
+import triton
+import triton.language as tl
+from torch.cuda.amp import custom_bwd, custom_fwd
+
+from . import custom_autotune
+
+
+logger = getLogger(__name__)
+
+
+# code based https://github.com/fpgaminer/GPTQ-triton
+
+
+@custom_autotune.autotune(
+ configs=[
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 64,
+ "BLOCK_SIZE_N": 256,
+ "BLOCK_SIZE_K": 32,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ),
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 128,
+ "BLOCK_SIZE_N": 128,
+ "BLOCK_SIZE_K": 32,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ),
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 64,
+ "BLOCK_SIZE_N": 128,
+ "BLOCK_SIZE_K": 32,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ),
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 128,
+ "BLOCK_SIZE_N": 32,
+ "BLOCK_SIZE_K": 32,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ),
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 64,
+ "BLOCK_SIZE_N": 64,
+ "BLOCK_SIZE_K": 32,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ),
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 64,
+ "BLOCK_SIZE_N": 128,
+ "BLOCK_SIZE_K": 32,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=2,
+ num_warps=8,
+ ),
+ ],
+ key=["M", "N", "K"],
+ nearest_power_of_two=True,
+ prune_configs_by={
+ "early_config_prune": custom_autotune.matmul248_kernel_config_pruner,
+ "perf_model": None,
+ "top_k": None,
+ },
+)
+@triton.jit
+def quant_matmul_248_kernel(
+ a_ptr,
+ b_ptr,
+ c_ptr,
+ scales_ptr,
+ zeros_ptr,
+ g_ptr,
+ M,
+ N,
+ K,
+ bits,
+ maxq,
+ stride_am,
+ stride_ak,
+ stride_bk,
+ stride_bn,
+ stride_cm,
+ stride_cn,
+ stride_scales,
+ stride_zeros,
+ BLOCK_SIZE_M: tl.constexpr,
+ BLOCK_SIZE_N: tl.constexpr,
+ BLOCK_SIZE_K: tl.constexpr,
+ GROUP_SIZE_M: tl.constexpr,
+):
+ """
+ Compute the matrix multiplication C = A x B.
+ A is of shape (M, K) float16
+ B is of shape (K//8, N) int32
+ C is of shape (M, N) float16
+ scales is of shape (G, N) float16
+ zeros is of shape (G, N) float16
+ g_ptr is of shape (K) int32
+ """
+ infearure_per_bits = 32 // bits
+
+ pid = tl.program_id(axis=0)
+ num_pid_m = tl.cdiv(M, BLOCK_SIZE_M)
+ num_pid_n = tl.cdiv(N, BLOCK_SIZE_N)
+ num_pid_k = tl.cdiv(K, BLOCK_SIZE_K)
+ num_pid_in_group = GROUP_SIZE_M * num_pid_n
+ group_id = pid // num_pid_in_group
+ first_pid_m = group_id * GROUP_SIZE_M
+ group_size_m = min(num_pid_m - first_pid_m, GROUP_SIZE_M)
+ pid_m = first_pid_m + (pid % group_size_m)
+ pid_n = (pid % num_pid_in_group) // group_size_m
+
+ offs_am = pid_m * BLOCK_SIZE_M + tl.arange(0, BLOCK_SIZE_M)
+ offs_bn = pid_n * BLOCK_SIZE_N + tl.arange(0, BLOCK_SIZE_N)
+ offs_k = tl.arange(0, BLOCK_SIZE_K)
+ a_ptrs = a_ptr + (offs_am[:, None] * stride_am + offs_k[None, :] * stride_ak) # (BLOCK_SIZE_M, BLOCK_SIZE_K)
+ a_mask = offs_am[:, None] < M
+ # b_ptrs is set up such that it repeats elements along the K axis 8 times
+ b_ptrs = b_ptr + (
+ (offs_k[:, None] // infearure_per_bits) * stride_bk + offs_bn[None, :] * stride_bn
+ ) # (BLOCK_SIZE_K, BLOCK_SIZE_N)
+ g_ptrs = g_ptr + offs_k
+ # shifter is used to extract the N bits of each element in the 32-bit word from B
+ scales_ptrs = scales_ptr + offs_bn[None, :]
+ zeros_ptrs = zeros_ptr + (offs_bn[None, :] // infearure_per_bits)
+
+ shifter = (offs_k % infearure_per_bits) * bits
+ zeros_shifter = (offs_bn % infearure_per_bits) * bits
+ accumulator = tl.zeros((BLOCK_SIZE_M, BLOCK_SIZE_N), dtype=tl.float32)
+
+ for k in range(0, num_pid_k):
+ g_idx = tl.load(g_ptrs)
+
+ # Fetch scales and zeros; these are per-outfeature and thus reused in the inner loop
+ scales = tl.load(scales_ptrs + g_idx[:, None] * stride_scales) # (BLOCK_SIZE_K, BLOCK_SIZE_N,)
+ zeros = tl.load(zeros_ptrs + g_idx[:, None] * stride_zeros) # (BLOCK_SIZE_K, BLOCK_SIZE_N,)
+
+ zeros = (zeros >> zeros_shifter[None, :]) & maxq
+ zeros = zeros + 1
+
+ a = tl.load(a_ptrs, mask=a_mask, other=0.0) # (BLOCK_SIZE_M, BLOCK_SIZE_K)
+ b = tl.load(b_ptrs) # (BLOCK_SIZE_K, BLOCK_SIZE_N), but repeated
+
+ # Now we need to unpack b (which is N-bit values) into 32-bit values
+ b = (b >> shifter[:, None]) & maxq # Extract the N-bit values
+ b = (b - zeros) * scales # Scale and shift
+
+ accumulator += tl.dot(a, b)
+ a_ptrs += BLOCK_SIZE_K
+ b_ptrs += (BLOCK_SIZE_K // infearure_per_bits) * stride_bk
+ g_ptrs += BLOCK_SIZE_K
+
+ c_ptrs = c_ptr + stride_cm * offs_am[:, None] + stride_cn * offs_bn[None, :]
+ c_mask = (offs_am[:, None] < M) & (offs_bn[None, :] < N)
+ tl.store(c_ptrs, accumulator, mask=c_mask)
+
+
+@custom_autotune.autotune(
+ configs=[
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 64,
+ "BLOCK_SIZE_N": 32,
+ "BLOCK_SIZE_K": 256,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ),
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 128,
+ "BLOCK_SIZE_N": 32,
+ "BLOCK_SIZE_K": 128,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ),
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 64,
+ "BLOCK_SIZE_N": 32,
+ "BLOCK_SIZE_K": 128,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ),
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 128,
+ "BLOCK_SIZE_N": 32,
+ "BLOCK_SIZE_K": 32,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ),
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 64,
+ "BLOCK_SIZE_N": 32,
+ "BLOCK_SIZE_K": 64,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=4,
+ num_warps=4,
+ ),
+ triton.Config(
+ {
+ "BLOCK_SIZE_M": 64,
+ "BLOCK_SIZE_N": 32,
+ "BLOCK_SIZE_K": 128,
+ "GROUP_SIZE_M": 8,
+ },
+ num_stages=2,
+ num_warps=8,
+ ),
+ ],
+ key=["M", "N", "K"],
+ nearest_power_of_two=True,
+)
+@triton.jit
+def transpose_quant_matmul_248_kernel(
+ a_ptr,
+ b_ptr,
+ c_ptr,
+ scales_ptr,
+ zeros_ptr,
+ g_ptr,
+ M,
+ N,
+ K,
+ bits,
+ maxq,
+ stride_am,
+ stride_ak,
+ stride_bk,
+ stride_bn,
+ stride_cm,
+ stride_cn,
+ stride_scales,
+ stride_zeros,
+ BLOCK_SIZE_M: tl.constexpr,
+ BLOCK_SIZE_N: tl.constexpr,
+ BLOCK_SIZE_K: tl.constexpr,
+ GROUP_SIZE_M: tl.constexpr,
+):
+ """
+ Compute the matrix multiplication C = A x B.
+ A is of shape (M, N) float16
+ B is of shape (K//8, N) int32
+ C is of shape (M, K) float16
+ scales is of shape (G, N) float16
+ zeros is of shape (G, N) float16
+ g_ptr is of shape (K) int32
+ """
+ infearure_per_bits = 32 // bits
+
+ pid = tl.program_id(axis=0)
+ num_pid_m = tl.cdiv(M, BLOCK_SIZE_M)
+ num_pid_k = tl.cdiv(K, BLOCK_SIZE_K)
+ num_pid_n = tl.cdiv(N, BLOCK_SIZE_N)
+ num_pid_in_group = GROUP_SIZE_M * num_pid_k
+ group_id = pid // num_pid_in_group
+ first_pid_m = group_id * GROUP_SIZE_M
+ group_size_m = min(num_pid_m - first_pid_m, GROUP_SIZE_M)
+ pid_m = first_pid_m + (pid % group_size_m)
+ pid_k = (pid % num_pid_in_group) // group_size_m
+
+ offs_am = pid_m * BLOCK_SIZE_M + tl.arange(0, BLOCK_SIZE_M)
+ offs_bk = pid_k * BLOCK_SIZE_K + tl.arange(0, BLOCK_SIZE_K)
+ offs_n = tl.arange(0, BLOCK_SIZE_N)
+ a_ptrs = a_ptr + (offs_am[:, None] * stride_am + offs_n[None, :] * stride_ak) # (BLOCK_SIZE_M, BLOCK_SIZE_N)
+ a_mask = offs_am[:, None] < M
+ # b_ptrs is set up such that it repeats elements along the K axis 8 times
+ b_ptrs = b_ptr + (
+ (offs_bk[:, None] // infearure_per_bits) * stride_bk + offs_n[None, :] * stride_bn
+ ) # (BLOCK_SIZE_K, BLOCK_SIZE_N)
+ g_ptrs = g_ptr + offs_bk
+ g_idx = tl.load(g_ptrs)
+
+ # shifter is used to extract the N bits of each element in the 32-bit word from B
+ scales_ptrs = scales_ptr + offs_n[None, :] + g_idx[:, None] * stride_scales
+ zeros_ptrs = zeros_ptr + (offs_n[None, :] // infearure_per_bits) + g_idx[:, None] * stride_zeros
+
+ shifter = (offs_bk % infearure_per_bits) * bits
+ zeros_shifter = (offs_n % infearure_per_bits) * bits
+ accumulator = tl.zeros((BLOCK_SIZE_M, BLOCK_SIZE_K), dtype=tl.float32)
+
+ for k in range(0, num_pid_n):
+ # Fetch scales and zeros; these are per-outfeature and thus reused in the inner loop
+ scales = tl.load(scales_ptrs) # (BLOCK_SIZE_K, BLOCK_SIZE_N,)
+ zeros = tl.load(zeros_ptrs) # (BLOCK_SIZE_K, BLOCK_SIZE_N,)
+
+ zeros = (zeros >> zeros_shifter[None, :]) & maxq
+ zeros = zeros + 1
+
+ a = tl.load(a_ptrs, mask=a_mask, other=0.0) # (BLOCK_SIZE_M, BLOCK_SIZE_N)
+ b = tl.load(b_ptrs) # (BLOCK_SIZE_K, BLOCK_SIZE_N), but repeated
+
+ # Now we need to unpack b (which is N-bit values) into 32-bit values
+ b = (b >> shifter[:, None]) & maxq # Extract the N-bit values
+ b = (b - zeros) * scales # Scale and shift
+ b = tl.trans(b)
+
+ accumulator += tl.dot(a, b)
+ a_ptrs += BLOCK_SIZE_N
+ b_ptrs += BLOCK_SIZE_N
+ scales_ptrs += BLOCK_SIZE_N
+ zeros_ptrs += BLOCK_SIZE_N // infearure_per_bits
+
+ c_ptrs = c_ptr + stride_cm * offs_am[:, None] + stride_cn * offs_bk[None, :]
+ c_mask = (offs_am[:, None] < M) & (offs_bk[None, :] < K)
+ tl.store(c_ptrs, accumulator, mask=c_mask)
+
+
+@triton.jit
+def silu(x):
+ return x * tl.sigmoid(x)
+
+
+def quant_matmul_248(input, qweight, scales, qzeros, g_idx, bits, maxq):
+ with torch.cuda.device(input.device):
+ output = torch.empty((input.shape[0], qweight.shape[1]), device=input.device, dtype=input.dtype)
+ grid = lambda META: ( # noqa: E731
+ triton.cdiv(input.shape[0], META["BLOCK_SIZE_M"]) * triton.cdiv(qweight.shape[1], META["BLOCK_SIZE_N"]),
+ )
+ quant_matmul_248_kernel[grid](
+ input,
+ qweight,
+ output,
+ scales.to(input.dtype),
+ qzeros,
+ g_idx,
+ input.shape[0],
+ qweight.shape[1],
+ input.shape[1],
+ bits,
+ maxq,
+ input.stride(0),
+ input.stride(1),
+ qweight.stride(0),
+ qweight.stride(1),
+ output.stride(0),
+ output.stride(1),
+ scales.stride(0),
+ qzeros.stride(0),
+ )
+ return output
+
+
+def transpose_quant_matmul_248(input, qweight, scales, qzeros, g_idx, bits, maxq):
+ with torch.cuda.device(input.device):
+ output_dim = (qweight.shape[0] * 32) // bits
+ output = torch.empty((input.shape[0], output_dim), device=input.device, dtype=input.dtype)
+ grid = lambda META: ( # noqa: E731
+ triton.cdiv(input.shape[0], META["BLOCK_SIZE_M"]) * triton.cdiv(output_dim, META["BLOCK_SIZE_K"]),
+ )
+ transpose_quant_matmul_248_kernel[grid](
+ input,
+ qweight,
+ output,
+ scales.to(input.dtype),
+ qzeros,
+ g_idx,
+ input.shape[0],
+ qweight.shape[1],
+ output_dim,
+ bits,
+ maxq,
+ input.stride(0),
+ input.stride(1),
+ qweight.stride(0),
+ qweight.stride(1),
+ output.stride(0),
+ output.stride(1),
+ scales.stride(0),
+ qzeros.stride(0),
+ )
+ return output
+
+
+class QuantLinearFunction(torch.autograd.Function):
+ @staticmethod
+ @custom_fwd
+ def forward(ctx, input, qweight, scales, qzeros, g_idx, bits, maxq):
+ output = quant_matmul_248(input, qweight, scales, qzeros, g_idx, bits, maxq)
+ ctx.save_for_backward(qweight, scales, qzeros, g_idx)
+ ctx.bits, ctx.maxq = bits, maxq
+ return output
+
+ @staticmethod
+ @custom_bwd
+ def backward(ctx, grad_output):
+ qweight, scales, qzeros, g_idx = ctx.saved_tensors
+ bits, maxq = ctx.bits, ctx.maxq
+ grad_input = None
+
+ if ctx.needs_input_grad[0]:
+ grad_input = transpose_quant_matmul_248(grad_output, qweight, scales, qzeros, g_idx, bits, maxq)
+ return grad_input, None, None, None, None, None, None
+
+
+def quant_matmul_inference_only_248(input, qweight, scales, qzeros, g_idx, bits, maxq):
+ with torch.cuda.device(input.device):
+ output = torch.empty((input.shape[0], qweight.shape[1]), device=input.device, dtype=torch.float16)
+ grid = lambda META: ( # noqa: E731
+ triton.cdiv(input.shape[0], META["BLOCK_SIZE_M"]) * triton.cdiv(qweight.shape[1], META["BLOCK_SIZE_N"]),
+ )
+ quant_matmul_248_kernel[grid](
+ input,
+ qweight,
+ output,
+ scales,
+ qzeros,
+ g_idx,
+ input.shape[0],
+ qweight.shape[1],
+ input.shape[1],
+ bits,
+ maxq,
+ input.stride(0),
+ input.stride(1),
+ qweight.stride(0),
+ qweight.stride(1),
+ output.stride(0),
+ output.stride(1),
+ scales.stride(0),
+ qzeros.stride(0),
+ )
+ return output
+
+
+class QuantLinearInferenceOnlyFunction(torch.autograd.Function):
+ @staticmethod
+ @custom_fwd(cast_inputs=torch.float16)
+ def forward(ctx, input, qweight, scales, qzeros, g_idx, bits, maxq):
+ output = quant_matmul_248(input, qweight, scales, qzeros, g_idx, bits, maxq)
+ return output
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/triton_utils/mixin.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/triton_utils/mixin.py
new file mode 100644
index 0000000000000000000000000000000000000000..16161183836589522d5a6f014bdcf66c1c6e0205
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/nn_modules/triton_utils/mixin.py
@@ -0,0 +1,4 @@
+class TritonModuleMixin:
+ @classmethod
+ def warmup(cls, model, transpose=False, seqlen=2048):
+ pass
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/quantization/ACKNOWLEDGEMENT.md b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/quantization/ACKNOWLEDGEMENT.md
new file mode 100644
index 0000000000000000000000000000000000000000..7c8dedc55228a902b2263c2f222a7fbb8342ae48
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/quantization/ACKNOWLEDGEMENT.md
@@ -0,0 +1 @@
+The codes in this directory are mainly referenced from @qwopqwop200 's [GPTQ-for-LLaMa](https://github.com/qwopqwop200/GPTQ-for-LLaMa/tree/cuda), which itself is based on [gptq](https://github.com/IST-DASLab/gptq)
\ No newline at end of file
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/quantization/__init__.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/quantization/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..1d0e82be090fecb8c38912eac130306463f3bb0b
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/quantization/__init__.py
@@ -0,0 +1,11 @@
+from .config import (
+ CHECKPOINT_FORMAT,
+ CHECKPOINT_FORMAT_FIELD,
+ CHECKPOINT_FORMAT_FIELD_COMPAT_MARLIN,
+ QUANT_CONFIG_FILENAME,
+ QUANT_METHOD,
+ QUANT_METHOD_FIELD,
+ BaseQuantizeConfig,
+)
+from .gptq import GPTQ
+from .quantizer import Quantizer, quantize
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/quantization/config.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/quantization/config.py
new file mode 100644
index 0000000000000000000000000000000000000000..f436db6dae8c094459a851f6c15d519e494b58d6
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/quantization/config.py
@@ -0,0 +1,258 @@
+import json
+import logging
+import os
+from dataclasses import dataclass, field, fields
+from os.path import isdir, join
+from typing import Optional
+
+import huggingface_hub
+from transformers.utils.hub import PushToHubMixin, cached_file
+
+
+logger = logging.getLogger(__name__)
+handler = logging.StreamHandler()
+formatter = logging.Formatter("%(levelname)s - %(message)s")
+handler.setFormatter(formatter)
+logger.propagate = False
+logger.addHandler(handler)
+logger.setLevel(logging.INFO)
+
+CHECKPOINT_FORMAT_FIELD = "checkpoint_format"
+CHECKPOINT_FORMAT_FIELD_COMPAT_MARLIN = "is_marlin_format"
+QUANT_METHOD_FIELD = "quant_method"
+QUANT_CONFIG_FILENAME = "quantize_config.json"
+
+
+# checkpoint formats
+class CHECKPOINT_FORMAT:
+ GPTQ = "gptq"
+ MARLIN = "marlin"
+ AWQ_GEMM = "gemm"
+
+
+# quant methods
+class QUANT_METHOD:
+ GPTQ = "gptq"
+ AWQ = "awq"
+
+
+QUANT_METHOD_FORMAT_MAPPING = {
+ QUANT_METHOD.GPTQ: {
+ CHECKPOINT_FORMAT.GPTQ,
+ CHECKPOINT_FORMAT.MARLIN,
+ },
+ QUANT_METHOD.AWQ: {
+ CHECKPOINT_FORMAT.AWQ_GEMM
+ }
+}
+
+# awq is inference only
+QUANTIZE_BLACK_LIST = {QUANT_METHOD.AWQ}
+
+# compat
+QUANT_CONFIG_ARG_SYNONYMS = {
+ "w_bit": "bits",
+ "q_group_size": "group_size",
+}
+
+
+@dataclass
+class BaseQuantizeConfig(PushToHubMixin):
+ bits: int = field(default=4, metadata={"choices": [2, 3, 4, 8]})
+ group_size: int = field(default=-1)
+ damp_percent: float = field(default=0.01)
+ desc_act: bool = field(default=True)
+ static_groups: bool = field(default=False)
+ sym: bool = field(default=True)
+ true_sequential: bool = field(default=True)
+ quant_method: str = field(default=QUANT_METHOD.GPTQ)
+ checkpoint_format: str = field(default=CHECKPOINT_FORMAT.GPTQ)
+ model_name_or_path: Optional[str] = field(default=None)
+ model_file_base_name: Optional[str] = field(default=None)
+
+ def __post_init__(self):
+ fields_info = fields(self)
+
+ # validate quant method and format is matched
+ valid_checkpoint_formats = QUANT_METHOD_FORMAT_MAPPING.get(self.quant_method, None)
+ if valid_checkpoint_formats is None:
+ raise ValueError(f"Unsupported quantization method: {self.quant_method}")
+
+ if self.checkpoint_format not in valid_checkpoint_formats:
+ raise ValueError(
+ f"The checkpoint format used is {self.checkpoint_format}, and the quantization method is {self.quant_method}. "
+ f"This is not supported, please open an issue at https://github.com/AutoGPTQ/AutoGPTQ/issues.")
+
+ if self.bits not in fields_info[0].metadata["choices"]:
+ raise ValueError(f"only support quantize to {fields_info[0].metadata['choices']} bits.")
+
+ if self.group_size != -1 and self.group_size <= 0:
+ raise ValueError("unless equal to -1, group_size must greater then 0.")
+
+ if not (0 < self.damp_percent < 1):
+ raise ValueError("damp_percent must between 0 and 1.")
+
+ def save_pretrained(self, save_dir: str, **kwargs):
+ with open(join(save_dir, QUANT_CONFIG_FILENAME), "w", encoding="utf-8") as f:
+ json.dump(self.to_dict(), f, indent=2)
+
+ @classmethod
+ # normalize quant config for compat and also performs validation
+ def from_quant_config(cls, quantize_cfg, checkpoint_format: str = None):
+ valid_formats = {CHECKPOINT_FORMAT.GPTQ, CHECKPOINT_FORMAT.MARLIN, CHECKPOINT_FORMAT.AWQ_GEMM}
+
+ checkpoint_format_auto_inferred = False
+ # compat: checkpoint_format can be passed in via from_quantized() if field missing from json
+ if checkpoint_format:
+ if checkpoint_format not in valid_formats:
+ raise ValueError(f"Unknown quantization checkpoint format: {checkpoint_format}.")
+ if quantize_cfg.get(CHECKPOINT_FORMAT_FIELD):
+ raise ValueError("Conflict: quantization checkpoint_format is passed in and also exists in model config.")
+ # compat: warn if checkpoint_format is missing
+ elif quantize_cfg.get(CHECKPOINT_FORMAT_FIELD) is None:
+ checkpoint_format_auto_inferred = True
+
+ field_names = [field.name for field in fields(cls)]
+
+ normalized = {QUANT_METHOD_FIELD: QUANT_METHOD.GPTQ, CHECKPOINT_FORMAT_FIELD: checkpoint_format if checkpoint_format else CHECKPOINT_FORMAT.GPTQ}
+ for key, val in quantize_cfg.items():
+ key = key.lower()
+
+ # remap keys according to compat map
+ if key in QUANT_CONFIG_ARG_SYNONYMS and QUANT_CONFIG_ARG_SYNONYMS[key] in field_names:
+ key = QUANT_CONFIG_ARG_SYNONYMS[key]
+
+ if key == CHECKPOINT_FORMAT_FIELD:
+ val = val.lower()
+
+ if val in {CHECKPOINT_FORMAT.GPTQ, CHECKPOINT_FORMAT.MARLIN, CHECKPOINT_FORMAT.AWQ_GEMM}:
+ normalized[key] = val
+ else:
+ raise ValueError(f"Unknown quantization format: {val}.")
+ elif key == QUANT_METHOD_FIELD:
+ val = val.lower()
+ # compat: some hf models use quant_method=marlin
+ if val == CHECKPOINT_FORMAT.MARLIN:
+ normalized[CHECKPOINT_FORMAT_FIELD] = CHECKPOINT_FORMAT.MARLIN
+ elif val not in {QUANT_METHOD.GPTQ, QUANT_METHOD.AWQ}:
+ raise ValueError(f"Unknown quantization method: {val}.")
+ else:
+ normalized[QUANT_METHOD_FIELD] = val
+ elif key == CHECKPOINT_FORMAT_FIELD_COMPAT_MARLIN and val:
+ normalized[CHECKPOINT_FORMAT_FIELD] = CHECKPOINT_FORMAT.MARLIN
+ elif key == "version" and val.lower() == CHECKPOINT_FORMAT.AWQ_GEMM:
+ normalized[QUANT_METHOD_FIELD] = QUANT_METHOD.AWQ
+ normalized[CHECKPOINT_FORMAT_FIELD] = CHECKPOINT_FORMAT.AWQ_GEMM
+ elif key in field_names:
+ normalized[key] = val
+ else:
+ logger.info(f"Ignoring unknown parameter in the quantization configuration: {key}.")
+
+ if checkpoint_format_auto_inferred:
+ logger.info(f"`checkpoint_format` is missing from the quantization configuration and is automatically inferred to {normalized[CHECKPOINT_FORMAT_FIELD]}.")
+
+ if normalized[CHECKPOINT_FORMAT_FIELD] in {CHECKPOINT_FORMAT.AWQ_GEMM, CHECKPOINT_FORMAT.MARLIN}:
+ # AWQ and Marlin do not reorder the rows.
+ normalized["desc_act"] = False
+
+ if "sym" not in normalized:
+ logger.warning(
+ "The quantization configuration does not contain an entry `sym` (symmetric quantization). "
+ "This may result in silent errors. Defaulting to `sym=True`."
+ )
+
+ return cls(**normalized)
+
+ @classmethod
+ def from_pretrained(cls, save_dir: str, **kwargs):
+ # Parameters related to loading from Hugging Face Hub
+ cache_dir = kwargs.pop("cache_dir", None)
+ force_download = kwargs.pop("force_download", False)
+ resume_download = kwargs.pop("resume_download", False)
+ proxies = kwargs.pop("proxies", None)
+ local_files_only = kwargs.pop("local_files_only", False)
+ use_auth_token = kwargs.pop("use_auth_token", None)
+ revision = kwargs.pop("revision", None)
+ subfolder = kwargs.pop("subfolder", None)
+ commit_hash = kwargs.pop("_commit_hash", None)
+ checkpoint_format = kwargs.pop("checkpoint_format", None)
+
+ transformers_config = False
+ for quantize_config_filename in [
+ QUANT_CONFIG_FILENAME,
+ "quant_config.json",
+ "config.json",
+ ]:
+ if isdir(save_dir): # Local
+ resolved_config_file = join(save_dir, quantize_config_filename)
+ else: # Remote
+ resolved_config_file = cached_file(
+ save_dir,
+ quantize_config_filename,
+ cache_dir=cache_dir,
+ force_download=force_download,
+ resume_download=resume_download,
+ proxies=proxies,
+ use_auth_token=use_auth_token,
+ revision=revision,
+ local_files_only=local_files_only,
+ subfolder=subfolder,
+ _raise_exceptions_for_missing_entries=False,
+ _raise_exceptions_for_connection_errors=False,
+ _commit_hash=commit_hash,
+ )
+ if resolved_config_file is not None:
+ if quantize_config_filename == "config.json":
+ transformers_config = True
+ break
+
+ if resolved_config_file is None:
+ raise ValueError(
+ "No quantize_config.json, quant_config.json or config.json file was found in the model repository."
+ )
+
+ with open(resolved_config_file, "r", encoding="utf-8") as f:
+ args_from_json = json.load(f)
+
+ if transformers_config:
+ args_from_json = args_from_json["quantization_config"]
+
+ return cls.from_quant_config(args_from_json, checkpoint_format)
+
+ def get_cache_file_path(self, quant_method: QUANT_METHOD = None, checkpoint_format: CHECKPOINT_FORMAT = None):
+ """
+ Gets The Cached Weight Path.
+ If remote: $HF_HOME/assets/autogptq/{model_name_or_path}/_{quant-method}_{checkpoint_format}.safetensors
+ If local: {model_name_or_path}/autogptq_model_{quant-method}_{checkpoint_format}.safetensors
+ """
+
+ use_quant_method = quant_method if quant_method else self.quant_method
+ use_checkpoint_format = checkpoint_format if checkpoint_format else self.checkpoint_format
+
+ cache_file_name = f"autogptq_model_{use_quant_method}_{use_checkpoint_format}.safetensors"
+
+ if os.path.isdir(self.model_name_or_path):
+ cache_file_name = os.path.join(self.model_name_or_path, cache_file_name)
+ else:
+ namespace, subfolder = self.model_name_or_path.split("/")
+ assets_path = huggingface_hub.cached_assets_path(
+ library_name="auto_gptq", namespace=namespace, subfolder=subfolder
+ )
+ cache_file_name = os.path.join(assets_path, cache_file_name)
+
+ return cache_file_name, os.path.isfile(cache_file_name)
+
+ def to_dict(self):
+ return {
+ "bits": self.bits,
+ "group_size": self.group_size,
+ "damp_percent": self.damp_percent,
+ "desc_act": self.desc_act,
+ "static_groups": self.static_groups,
+ "sym": self.sym,
+ "true_sequential": self.true_sequential,
+ "model_name_or_path": self.model_name_or_path,
+ "model_file_base_name": self.model_file_base_name,
+ QUANT_METHOD_FIELD: self.quant_method,
+ CHECKPOINT_FORMAT_FIELD: self.checkpoint_format,
+ }
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/quantization/gptq.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/quantization/gptq.py
new file mode 100644
index 0000000000000000000000000000000000000000..cda3e7acff29d0426c8153d2483b7261fe4b0811
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/quantization/gptq.py
@@ -0,0 +1,206 @@
+import math
+import os
+import time
+from logging import getLogger
+
+import torch
+import torch.nn as nn
+import transformers
+
+from .quantizer import Quantizer
+
+
+logger = getLogger(__name__)
+
+torch.backends.cuda.matmul.allow_tf32 = False
+torch.backends.cudnn.allow_tf32 = False
+
+
+class GPTQ:
+ def __init__(self, layer):
+ self.layer = layer
+ self.dev = self.layer.weight.device
+ W = layer.weight.data.clone()
+ if isinstance(self.layer, nn.Conv2d):
+ W = W.flatten(1)
+ if isinstance(self.layer, transformers.pytorch_utils.Conv1D):
+ W = W.t()
+ self.rows = W.shape[0]
+ self.columns = W.shape[1]
+ self.H = torch.zeros((self.columns, self.columns), device=self.dev)
+ self.nsamples = 0
+ self.quantizer = Quantizer()
+
+ def add_batch(self, inp, out):
+ if os.environ.get("DEBUG"):
+ self.inp1 = inp
+ self.out1 = out
+ if len(inp.shape) == 2:
+ inp = inp.unsqueeze(0)
+ tmp = inp.shape[0]
+ if isinstance(self.layer, nn.Linear) or isinstance(self.layer, transformers.Conv1D):
+ if len(inp.shape) == 3:
+ inp = inp.reshape((-1, inp.shape[-1]))
+ inp = inp.t()
+ if isinstance(self.layer, nn.Conv2d):
+ unfold = nn.Unfold(
+ self.layer.kernel_size,
+ dilation=self.layer.dilation,
+ padding=self.layer.padding,
+ stride=self.layer.stride,
+ )
+ inp = unfold(inp)
+ inp = inp.permute([1, 0, 2])
+ inp = inp.flatten(1)
+ self.H *= self.nsamples / (self.nsamples + tmp)
+ self.nsamples += tmp
+ # inp = inp.float()
+ inp = math.sqrt(2 / self.nsamples) * inp.float()
+ # self.H += 2 / self.nsamples * inp.matmul(inp.t())
+ self.H += inp.matmul(inp.t())
+
+ def fasterquant(
+ self,
+ blocksize=128,
+ percdamp=0.01,
+ group_size=-1,
+ actorder=False,
+ static_groups=False,
+ ):
+ W = self.layer.weight.data.clone()
+ if isinstance(self.layer, nn.Conv2d):
+ W = W.flatten(1)
+ if isinstance(self.layer, transformers.Conv1D):
+ W = W.t()
+ W = W.float()
+
+ tick = time.time()
+
+ if not self.quantizer.ready():
+ self.quantizer.find_params(W, weight=True)
+
+ H = self.H
+ del self.H
+ dead = torch.diag(H) == 0
+ H[dead, dead] = 1
+ W[:, dead] = 0
+
+ g_idx = []
+ scale = []
+ zero = []
+ now_idx = 1
+
+ if static_groups:
+ import copy
+
+ groups = []
+ for i in range(0, self.columns, group_size):
+ quantizer = copy.deepcopy(self.quantizer)
+ quantizer.find_params(W[:, i : (i + group_size)], weight=True)
+ scale.append(quantizer.scale)
+ zero.append(quantizer.zero)
+ groups.append(quantizer)
+
+ if actorder:
+ perm = torch.argsort(torch.diag(H), descending=True)
+ W = W[:, perm]
+ H = H[perm][:, perm]
+ invperm = torch.argsort(perm)
+
+ Losses = torch.zeros_like(W)
+ Q = torch.zeros_like(W)
+
+ damp = percdamp * torch.mean(torch.diag(H))
+ diag = torch.arange(self.columns, device=self.dev)
+ H[diag, diag] += damp
+ H = torch.linalg.cholesky(H)
+ H = torch.cholesky_inverse(H)
+ H = torch.linalg.cholesky(H, upper=True)
+ Hinv = H
+
+ for i1 in range(0, self.columns, blocksize):
+ i2 = min(i1 + blocksize, self.columns)
+ count = i2 - i1
+
+ W1 = W[:, i1:i2].clone()
+ Q1 = torch.zeros_like(W1)
+ Err1 = torch.zeros_like(W1)
+ Losses1 = torch.zeros_like(W1)
+ Hinv1 = Hinv[i1:i2, i1:i2]
+
+ for i in range(count):
+ w = W1[:, i]
+ d = Hinv1[i, i]
+
+ if group_size != -1:
+ if not static_groups:
+ if (i1 + i) % group_size == 0:
+ self.quantizer.find_params(W[:, (i1 + i) : (i1 + i + group_size)], weight=True)
+
+ if ((i1 + i) // group_size) - now_idx == -1:
+ scale.append(self.quantizer.scale)
+ zero.append(self.quantizer.zero)
+ now_idx += 1
+ else:
+ idx = i1 + i
+ if actorder:
+ idx = perm[idx]
+ self.quantizer = groups[idx // group_size]
+
+ q = self.quantizer.quantize(w.unsqueeze(1)).flatten()
+ Q1[:, i] = q
+ Losses1[:, i] = (w - q) ** 2 / d**2
+
+ err1 = (w - q) / d
+ W1[:, i:] -= err1.unsqueeze(1).matmul(Hinv1[i, i:].unsqueeze(0))
+ Err1[:, i] = err1
+
+ Q[:, i1:i2] = Q1
+ Losses[:, i1:i2] = Losses1 / 2
+
+ W[:, i2:] -= Err1.matmul(Hinv[i1:i2, i2:])
+
+ if os.environ.get("DEBUG"):
+ self.layer.weight.data[:, :i2] = Q[:, :i2]
+ self.layer.weight.data[:, i2:] = W[:, i2:]
+ logger.debug(torch.sum((self.layer(self.inp1) - self.out1) ** 2))
+ logger.debug(torch.sum(Losses))
+
+ torch.cuda.synchronize()
+ logger.info(f"duration: {(time.time() - tick)}")
+ logger.info(f"avg loss: {torch.sum(Losses).item() / self.nsamples}")
+
+ group_size = group_size if group_size != -1 else self.columns
+ if static_groups and actorder:
+ g_idx = [perm[i] // group_size for i in range(self.columns)]
+ else:
+ g_idx = [i // group_size for i in range(self.columns)]
+ g_idx = torch.tensor(g_idx, dtype=torch.int32, device=Q.device)
+ if actorder:
+ Q = Q[:, invperm]
+ g_idx = g_idx[invperm]
+
+ if isinstance(self.layer, transformers.Conv1D):
+ Q = Q.t()
+ self.layer.weight.data = Q.reshape(self.layer.weight.shape).type_as(self.layer.weight.data)
+ if os.environ.get("DEBUG"):
+ logger.debug(torch.sum((self.layer(self.inp1) - self.out1) ** 2))
+
+ if scale == []:
+ scale.append(self.quantizer.scale)
+ zero.append(self.quantizer.zero)
+ scale = torch.cat(scale, dim=1)
+ zero = torch.cat(zero, dim=1)
+ return scale, zero, g_idx
+
+ def free(self):
+ if os.environ.get("DEBUG"):
+ self.inp1 = None
+ self.out1 = None
+ self.H = None
+ self.Losses = None
+ self.Trace = None
+ torch.cuda.empty_cache()
+
+
+__all__ = ["GPTQ"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/quantization/quantizer.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/quantization/quantizer.py
new file mode 100644
index 0000000000000000000000000000000000000000..e945a7040bdf045ef746ce8923af788874d91387
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/quantization/quantizer.py
@@ -0,0 +1,140 @@
+from logging import getLogger
+
+import torch
+import torch.nn as nn
+
+
+logger = getLogger(__name__)
+
+
+def quantize(x, scale, zero, maxq):
+ if maxq < 0:
+ return (x > scale / 2).float() * scale + (x < zero / 2).float() * zero
+ q = torch.clamp(torch.round(x / scale) + zero, 0, maxq)
+ return scale * (q - zero)
+
+
+class Quantizer(nn.Module):
+ def __init__(self, shape=1):
+ super(Quantizer, self).__init__()
+ self.register_buffer("maxq", torch.tensor(0))
+ self.register_buffer("scale", torch.zeros(shape))
+ self.register_buffer("zero", torch.zeros(shape))
+
+ def configure(
+ self,
+ bits,
+ perchannel=False,
+ sym=True,
+ mse=False,
+ norm=2.4,
+ grid=100,
+ maxshrink=0.8,
+ trits=False,
+ ):
+ self.maxq = torch.tensor(2**bits - 1)
+ self.perchannel = perchannel
+ self.sym = sym
+ self.mse = mse
+ self.norm = norm
+ self.grid = grid
+ self.maxshrink = maxshrink
+ if trits:
+ self.maxq = torch.tensor(-1)
+
+ def find_params(self, x, weight=False):
+ dev = x.device
+ self.maxq = self.maxq.to(dev)
+
+ shape = x.shape
+ if self.perchannel:
+ if weight:
+ x = x.flatten(1)
+ else:
+ if len(shape) == 4:
+ x = x.permute([1, 0, 2, 3])
+ x = x.flatten(1)
+ if len(shape) == 3:
+ x = x.reshape((-1, shape[-1])).t()
+ if len(shape) == 2:
+ x = x.t()
+ else:
+ x = x.flatten().unsqueeze(0)
+
+ tmp = torch.zeros(x.shape[0], device=dev)
+ xmin = torch.minimum(x.min(1)[0], tmp)
+ xmax = torch.maximum(x.max(1)[0], tmp)
+
+ if self.sym:
+ xmax = torch.maximum(torch.abs(xmin), xmax)
+ tmp = xmin < 0
+ if torch.any(tmp):
+ xmin[tmp] = -xmax[tmp]
+ tmp = (xmin == 0) & (xmax == 0)
+ xmin[tmp] = -1
+ xmax[tmp] = +1
+
+ if self.maxq < 0:
+ self.scale = xmax
+ self.zero = xmin
+ else:
+ self.scale = (xmax - xmin) / self.maxq
+ if self.sym:
+ self.zero = torch.full_like(self.scale, (self.maxq + 1) / 2)
+ else:
+ self.zero = torch.round(-xmin / self.scale)
+
+ if self.mse:
+ best = torch.full([x.shape[0]], float("inf"), device=dev)
+ for i in range(int(self.maxshrink * self.grid)):
+ p = 1 - i / self.grid
+ xmin1 = p * xmin
+ xmax1 = p * xmax
+ scale1 = (xmax1 - xmin1) / self.maxq
+ zero1 = torch.round(-xmin1 / scale1) if not self.sym else self.zero
+ q = quantize(x, scale1.unsqueeze(1), zero1.unsqueeze(1), self.maxq)
+ q -= x
+ q.abs_()
+ q.pow_(self.norm)
+ err = torch.sum(q, 1)
+ tmp = err < best
+ if torch.any(tmp):
+ best[tmp] = err[tmp]
+ self.scale[tmp] = scale1[tmp]
+ self.zero[tmp] = zero1[tmp]
+ if not self.perchannel:
+ if weight:
+ tmp = shape[0]
+ else:
+ tmp = shape[1] if len(shape) != 3 else shape[2]
+ self.scale = self.scale.repeat(tmp)
+ self.zero = self.zero.repeat(tmp)
+
+ if weight:
+ shape = [-1] + [1] * (len(shape) - 1)
+ self.scale = self.scale.reshape(shape)
+ self.zero = self.zero.reshape(shape)
+ return
+ if len(shape) == 4:
+ self.scale = self.scale.reshape((1, -1, 1, 1))
+ self.zero = self.zero.reshape((1, -1, 1, 1))
+ if len(shape) == 3:
+ self.scale = self.scale.reshape((1, 1, -1))
+ self.zero = self.zero.reshape((1, 1, -1))
+ if len(shape) == 2:
+ self.scale = self.scale.unsqueeze(0)
+ self.zero = self.zero.unsqueeze(0)
+
+ def quantize(self, x):
+ if self.ready():
+ return quantize(x, self.scale, self.zero, self.maxq)
+ return x
+
+ def enabled(self):
+ return self.maxq > 0
+
+ def ready(self):
+ return torch.all(self.scale != 0)
+
+
+__all__ = ["Quantizer"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/__init__.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..2f75305add3f6a92a87e9680ef8feab4766f03f6
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/__init__.py
@@ -0,0 +1 @@
+from .perplexity_utils import Perplexity
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/accelerate_utils.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/accelerate_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..15a4b94cc381a255a57419659a4edfca4f4908cd
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/accelerate_utils.py
@@ -0,0 +1,248 @@
+
+import gc
+import json
+import logging
+import os
+import shutil
+import tempfile
+from typing import Dict, List, Optional, Union
+
+import torch
+import torch.nn as nn
+from accelerate.utils.constants import SAFE_WEIGHTS_NAME, WEIGHTS_NAME
+from accelerate.utils.modeling import (
+ check_tied_parameters_in_config,
+ check_tied_parameters_on_same_device,
+ find_tied_parameters,
+ load_offloaded_weights,
+ load_state_dict,
+ retie_parameters,
+ set_module_tensor_to_device,
+)
+from accelerate.utils.offload import offload_weight, save_offload_index
+
+
+logger = logging.getLogger(__name__)
+
+# TODO: Remove and use instead accelerate.utils.modeling.load_checkpoint_in_model once https://github.com/huggingface/accelerate/pull/2588 is merged & accelerate 0.29 is released.
+def load_checkpoint_in_model(
+ model: nn.Module,
+ checkpoint: Union[str, os.PathLike],
+ device_map: Optional[Dict[str, Union[int, str, torch.device]]] = None,
+ offload_folder: Optional[Union[str, os.PathLike]] = None,
+ dtype: Optional[Union[str, torch.dtype]] = None,
+ offload_state_dict: bool = False,
+ offload_buffers: bool = False,
+ keep_in_fp32_modules: List[str] = None,
+ offload_8bit_bnb: bool = False,
+ strict: bool = False,
+):
+ """
+ Loads a (potentially sharded) checkpoint inside a model, potentially sending weights to a given device as they are
+ loaded.
+
+
+
+ Once loaded across devices, you still need to call [`dispatch_model`] on your model to make it able to run. To
+ group the checkpoint loading and dispatch in one single call, use [`load_checkpoint_and_dispatch`].
+
+
+
+ Args:
+ model (`torch.nn.Module`):
+ The model in which we want to load a checkpoint.
+ checkpoint (`str` or `os.PathLike`):
+ The folder checkpoint to load. It can be:
+ - a path to a file containing a whole model state dict
+ - a path to a `.json` file containing the index to a sharded checkpoint
+ - a path to a folder containing a unique `.index.json` file and the shards of a checkpoint.
+ - a path to a folder containing a unique pytorch_model.bin or a model.safetensors file.
+ device_map (`Dict[str, Union[int, str, torch.device]]`, *optional*):
+ A map that specifies where each submodule should go. It doesn't need to be refined to each parameter/buffer
+ name, once a given module name is inside, every submodule of it will be sent to the same device.
+ offload_folder (`str` or `os.PathLike`, *optional*):
+ If the `device_map` contains any value `"disk"`, the folder where we will offload weights.
+ dtype (`str` or `torch.dtype`, *optional*):
+ If provided, the weights will be converted to that type when loaded.
+ offload_state_dict (`bool`, *optional*, defaults to `False`):
+ If `True`, will temporarily offload the CPU state dict on the hard drive to avoid getting out of CPU RAM if
+ the weight of the CPU state dict + the biggest shard does not fit.
+ offload_buffers (`bool`, *optional*, defaults to `False`):
+ Whether or not to include the buffers in the weights offloaded to disk.
+ keep_in_fp32_modules(`List[str]`, *optional*):
+ A list of the modules that we keep in `torch.float32` dtype.
+ offload_8bit_bnb (`bool`, *optional*):
+ Whether or not to enable offload of 8-bit modules on cpu/disk.
+ strict (`bool`, *optional*, defaults to `False`):
+ Whether to strictly enforce that the keys in the checkpoint state_dict match the keys of the model's state_dict.
+
+ """
+ if offload_8bit_bnb:
+ from accelerate.utils.bnb import quantize_and_offload_8bit
+
+ tied_params = find_tied_parameters(model)
+
+ if check_tied_parameters_in_config(model) and len(tied_params) == 0:
+ logger.warn(
+ "The model weights are not tied. Please use the `tie_weights` method before using the `infer_auto_device` function."
+ )
+ if device_map is not None:
+ check_tied_parameters_on_same_device(tied_params, device_map)
+
+ if offload_folder is None and device_map is not None and "disk" in device_map.values():
+ raise ValueError(
+ "At least one of the model submodule will be offloaded to disk, please pass along an `offload_folder`."
+ )
+ elif offload_folder is not None and device_map is not None and "disk" in device_map.values():
+ os.makedirs(offload_folder, exist_ok=True)
+
+ if isinstance(dtype, str):
+ # We accept "torch.float16" or just "float16"
+ dtype = dtype.replace("torch.", "")
+ dtype = getattr(torch, dtype)
+
+ checkpoint_files = None
+ index_filename = None
+ if os.path.isfile(checkpoint):
+ if str(checkpoint).endswith(".json"):
+ index_filename = checkpoint
+ else:
+ checkpoint_files = [checkpoint]
+ elif os.path.isdir(checkpoint):
+ # check if the whole state dict is present
+ potential_state_bin = [f for f in os.listdir(checkpoint) if f == WEIGHTS_NAME]
+ potential_state_safetensor = [f for f in os.listdir(checkpoint) if f == SAFE_WEIGHTS_NAME]
+ if len(potential_state_bin) == 1:
+ checkpoint_files = [os.path.join(checkpoint, potential_state_bin[0])]
+ elif len(potential_state_safetensor) == 1:
+ checkpoint_files = [os.path.join(checkpoint, potential_state_safetensor[0])]
+ else:
+ # otherwise check for sharded checkpoints
+ potential_index = [f for f in os.listdir(checkpoint) if f.endswith(".index.json")]
+ if len(potential_index) == 0:
+ raise ValueError(
+ f"{checkpoint} is not a folder containing a `.index.json` file or a {WEIGHTS_NAME} or a {SAFE_WEIGHTS_NAME} file"
+ )
+ elif len(potential_index) == 1:
+ index_filename = os.path.join(checkpoint, potential_index[0])
+ else:
+ raise ValueError(
+ f"{checkpoint} containing more than one `.index.json` file, delete the irrelevant ones."
+ )
+ else:
+ raise ValueError(
+ "`checkpoint` should be the path to a file containing a whole state dict, or the index of a sharded "
+ f"checkpoint, or a folder containing a sharded checkpoint or the whole state dict, but got {checkpoint}."
+ )
+
+ if index_filename is not None:
+ checkpoint_folder = os.path.split(index_filename)[0]
+ with open(index_filename) as f:
+ index = json.loads(f.read())
+
+ if "weight_map" in index:
+ index = index["weight_map"]
+ checkpoint_files = sorted(list(set(index.values()))) # noqa: C414
+ checkpoint_files = [os.path.join(checkpoint_folder, f) for f in checkpoint_files]
+
+ # Logic for missing/unexepected keys goes here.
+
+ offload_index = {}
+ if offload_state_dict:
+ state_dict_folder = tempfile.mkdtemp()
+ state_dict_index = {}
+
+ unexpected_keys = set()
+ model_keys = set(model.state_dict().keys())
+ buffer_names = [name for name, _ in model.named_buffers()]
+ for checkpoint_file in checkpoint_files:
+ loaded_checkpoint = load_state_dict(checkpoint_file, device_map=device_map)
+ if device_map is None:
+ model.load_state_dict(loaded_checkpoint, strict=strict)
+ unexpected_keys.update(set(loaded_checkpoint.keys()) - model_keys)
+ else:
+ for param_name, param in loaded_checkpoint.items():
+ # skip SCB parameter (for 8-bit serialization)
+ if "SCB" in param_name:
+ continue
+
+ if param_name not in model_keys:
+ unexpected_keys.add(param_name)
+ if not strict:
+ continue # Skip loading this parameter.
+
+ module_name = param_name
+
+ while len(module_name) > 0 and module_name not in device_map:
+ module_name = ".".join(module_name.split(".")[:-1])
+ if module_name == "" and "" not in device_map:
+ # TODO: group all errors and raise at the end.
+ raise ValueError(f"{param_name} doesn't have any device set.")
+ param_device = device_map[module_name]
+ new_dtype = dtype
+ if dtype is not None and torch.is_floating_point(param):
+ if keep_in_fp32_modules is not None and dtype == torch.float16:
+ proceed = False
+ for key in keep_in_fp32_modules:
+ if ((key in param_name) and (key + "." in param_name)) or key == param_name:
+ proceed = True
+ break
+ if proceed:
+ new_dtype = torch.float32
+
+ if "weight" in param_name and param_name.replace("weight", "SCB") in loaded_checkpoint.keys():
+ if param.dtype == torch.int8:
+ fp16_statistics = loaded_checkpoint[param_name.replace("weight", "SCB")]
+ else:
+ fp16_statistics = None
+
+ if param_device == "disk":
+ if offload_buffers or param_name not in buffer_names:
+ if new_dtype is None:
+ new_dtype = param.dtype
+ if offload_8bit_bnb:
+ quantize_and_offload_8bit(
+ model, param, param_name, new_dtype, offload_folder, offload_index, fp16_statistics
+ )
+ continue
+ else:
+ set_module_tensor_to_device(model, param_name, "meta", dtype=new_dtype)
+ offload_weight(param, param_name, offload_folder, index=offload_index)
+ elif param_device == "cpu" and offload_state_dict:
+ if new_dtype is None:
+ new_dtype = param.dtype
+ if offload_8bit_bnb:
+ quantize_and_offload_8bit(
+ model, param, param_name, new_dtype, state_dict_folder, state_dict_index, fp16_statistics
+ )
+ else:
+ set_module_tensor_to_device(model, param_name, "meta", dtype=new_dtype)
+ offload_weight(param, param_name, state_dict_folder, index=state_dict_index)
+ else:
+ set_module_tensor_to_device(
+ model,
+ param_name,
+ param_device,
+ value=param,
+ dtype=new_dtype,
+ fp16_statistics=fp16_statistics,
+ )
+
+ # Force Python to clean up.
+ del loaded_checkpoint
+ gc.collect()
+
+ if not strict and len(unexpected_keys) > 0:
+ logger.warning(
+ f"Some weights of the model checkpoint at {checkpoint} were not used when"
+ f" initializing {model.__class__.__name__}: {unexpected_keys}. This may or may not be an issue - make sure that the checkpoint does not have unnecessary parameters, or that the model definition correctly corresponds to the checkpoint."
+ )
+
+ save_offload_index(offload_index, offload_folder)
+
+ # Load back offloaded state dict on CPU
+ if offload_state_dict:
+ load_offloaded_weights(model, state_dict_index, state_dict_folder)
+ shutil.rmtree(state_dict_folder)
+
+ retie_parameters(model, tied_params)
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/data_utils.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/data_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..ba4222d32092ae352b5f8ca857f8d364224d4714
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/data_utils.py
@@ -0,0 +1,263 @@
+import copy
+import random
+from functools import partial
+from typing import Callable, Dict, List, Optional
+
+import torch
+from datasets import DatasetDict, IterableDatasetDict, load_dataset
+from torch import LongTensor
+from torch.utils.data import DataLoader
+from transformers import PreTrainedTokenizer
+
+
+def make_data_block(
+ samples: Dict[str, List[str]],
+ prompt_col_name: str,
+ label_col_name: str,
+ tokenizer: PreTrainedTokenizer,
+ preprocess_fn: Optional[Callable] = None,
+ sample_max_len: int = 1024,
+ block_max_len: int = 2048,
+ add_eos_token: bool = False,
+ truncate_prompt: bool = True,
+ merge_prompt_label: bool = False,
+) -> Dict[str, List[LongTensor]]:
+ """A simple implementation of text generation oriented smart batching to maximize VRAM usage when evaluation
+
+ :param samples: Dict[str, List[str]], samples that used to make data blocks
+ :param prompt_col_name: str, name of the key in samples whose value stores prompt
+ :param label_col_name: str, name of the key in samples whose value stores label
+ :param tokenizer: transformers.PretrainedTokenizer, tokenizer that used to tokenize samples
+ :param preprocess_fn: Optional[Callable], optional function that used to preprocess samples such as
+ refactor the data structure of samples, note the output of this function must be a dict whose keys
+ at least contains `prompt_col_name` and `label_col_name`
+ :param sample_max_len: int, defaults to 1024, max tokens number of each sample (before padding)
+ :param block_max_len: int, defaults to 2048, max tokens number of each data block (after padding)
+ :param add_eos_token: bool, defaults to False, whether add eos_token or not to the label
+ :param truncate_prompt: bool, defaults to True, whether to truncate prompt if the sample's total tokens
+ number exceeds `sample_max_len`, if not, will truncate label and drop this sample when all tokens
+ in label are truncated
+ :param merge_prompt_label: bool, defaults to False, will merge label into prompt if set to True, usually
+ this only required when doing language modeling task
+ :return: Dict[str, List[torch.LongTensor]], a dict whose keys are `input_ids`, `attention_mask` and
+ `label` and values are a list of torch.LongTensor
+ """
+ if preprocess_fn:
+ samples = preprocess_fn(samples)
+
+ prompts = samples[prompt_col_name]
+ labels = samples[label_col_name]
+
+ # tokenize samples
+ tokenized_prompts = tokenizer(prompts, truncation=False)["input_ids"]
+ tokenized_labels = tokenizer(labels, truncation=False)["input_ids"]
+
+ # filter tokenized samples by length
+ dropped_indices = []
+ for idx, (tokenized_prompt, tokenized_label) in enumerate(zip(tokenized_prompts, tokenized_labels)):
+ if add_eos_token:
+ tokenized_label += [tokenizer.eos_token_id]
+ len_prompt = len(tokenized_prompt)
+ len_label = len(tokenized_label)
+ exceed_len = len_prompt + len_label - sample_max_len
+ if exceed_len > 0:
+ if truncate_prompt:
+ tokenized_prompt = tokenized_prompt[exceed_len:]
+ else:
+ tokenized_label = tokenized_label[:-exceed_len]
+ tokenized_prompts[idx] = tokenized_prompt
+ tokenized_labels[idx] = tokenized_label
+ if not tokenized_label:
+ dropped_indices.append(idx)
+
+ # make data blocks of samples
+ tokenized_samples = sorted(
+ [(p, l) for idx, (p, l) in enumerate(zip(tokenized_prompts, tokenized_labels)) if idx not in dropped_indices],
+ key=lambda x: (len(x[0]) + len(x[1])) if merge_prompt_label else len(x[0]),
+ )
+ sample_blocks = []
+ sample_block = []
+ blk_max_len = 0
+ blk_total_len = 0
+ for tokenized_sample in tokenized_samples:
+ prompt_ids, label_ids = tokenized_sample
+ ori_sample_len = len(prompt_ids)
+ if merge_prompt_label:
+ ori_sample_len += len(label_ids)
+ if ori_sample_len <= blk_max_len:
+ additional_len = blk_max_len
+ sample_len = blk_max_len
+ else:
+ additional_len = len(sample_block) * (ori_sample_len - blk_max_len) + ori_sample_len
+ sample_len = ori_sample_len
+
+ if blk_total_len + additional_len > block_max_len:
+ sample_blocks.append((copy.copy(sample_block), blk_max_len))
+ sample_block = []
+ blk_max_len = 0
+ blk_total_len = 0
+ sample_len = ori_sample_len
+ additional_len = ori_sample_len
+
+ sample_block.append(tokenized_sample)
+ blk_max_len = max(blk_max_len, sample_len)
+ blk_total_len += additional_len
+
+ if sample_block:
+ sample_blocks.append((copy.copy(sample_block), blk_max_len))
+ del sample_block
+ del blk_max_len
+ del blk_total_len
+
+ new_samples = {"input_ids": [], "attention_mask": [], "labels": []}
+ # padding each data block internally
+ for block, blk_max_len in sample_blocks:
+ input_ids = []
+ attention_mask = []
+ label_ids = []
+ label_max_len = max([len(sample[1]) for sample in block])
+
+ for sample in block:
+ tokenized_prompt, tokenized_label = sample
+ sample_len = len(tokenized_prompt)
+ if merge_prompt_label:
+ sample_len += len(tokenized_label)
+ pad_num = blk_max_len - sample_len
+ if merge_prompt_label:
+ input_ids.append([tokenizer.pad_token_id] * pad_num + tokenized_prompt + tokenized_label)
+ label_ids.append([-100] * (pad_num + len(tokenized_prompt)) + tokenized_label)
+ else:
+ input_ids.append([tokenizer.pad_token_id] * pad_num + tokenized_prompt)
+ label_ids.append([-100] * (label_max_len - len(tokenized_label)) + tokenized_label)
+ attention_mask.append([0] * pad_num + [1] * sample_len)
+
+ new_samples["input_ids"].append(input_ids)
+ new_samples["attention_mask"].append(attention_mask)
+ new_samples["labels"].append(label_ids)
+
+ return new_samples
+
+
+def collate_data(blocks: List[Dict[str, List[List[int]]]], pad_token_id: int) -> Dict[str, LongTensor]:
+ def pad_block(block, pads):
+ return torch.cat((pads.to(block.device), block), dim=-1)
+
+ input_ids_blocks = [LongTensor(block["input_ids"]) for block in blocks]
+ attention_mask_blocks = [LongTensor(block["attention_mask"]) for block in blocks]
+ label_blocks = [LongTensor(block["labels"]) for block in blocks]
+
+ bsz = len(blocks)
+ inp_max_len = max([block.size(-1) for block in input_ids_blocks])
+ label_max_len = max([block.size(-1) for block in label_blocks])
+
+ for i in range(bsz):
+ block_bsz, block_inp_len = input_ids_blocks[i].shape
+ block_label_len = label_blocks[i].shape[-1]
+ pad_num = inp_max_len - block_inp_len
+ if pad_num > 0:
+ input_ids_blocks[i] = pad_block(input_ids_blocks[i], torch.ones((block_bsz, pad_num)) * pad_token_id)
+ attention_mask_blocks[i] = pad_block(attention_mask_blocks[i], torch.zeros((block_bsz, pad_num)))
+ label_pad_num = label_max_len - block_label_len
+ if label_pad_num > 0:
+ label_blocks[i] = pad_block(label_blocks[i], torch.ones((block_bsz, label_pad_num)) * -100)
+
+ return {
+ "input_ids": torch.cat(input_ids_blocks, dim=0).long(),
+ "attention_mask": torch.cat(attention_mask_blocks, dim=0).long(),
+ "labels": torch.cat(label_blocks, dim=0).long(),
+ }
+
+
+def get_dataloader(
+ data_path_or_name: str,
+ prompt_col_name: str,
+ label_col_name: str,
+ tokenizer: PreTrainedTokenizer,
+ load_fn: Optional[Callable] = None,
+ preprocess_fn: Optional[Callable] = None,
+ num_samples: int = 128,
+ sample_max_len: int = 1024,
+ block_max_len: int = 2048,
+ add_eos_token: bool = False,
+ truncate_prompt: bool = True,
+ merge_prompt_label: bool = False,
+ load_fn_kwargs: Optional[dict] = None,
+ preprocess_fn_kwargs: Optional[dict] = None,
+ **kwargs,
+) -> DataLoader:
+ """load dataset and build dataloader
+
+ :param data_path_or_name: str, dataset name in hf-hub or local file path
+ :param prompt_col_name: str, see `make_data_block`
+ :param label_col_name: str, see `make_data_block`
+ :param tokenizer: str, see `make_data_block`
+ :param load_fn: Optional[Callable], defaults to None, function used to load dataset, if not specified,
+ use `datasets.load_dataset`
+ :param preprocess_fn: Optional[Callable], see `make_data_block`
+ :param num_samples: int, defaults to 128, total samples used to evaluation
+ :param sample_max_len: int, see `make_data_block`
+ :param block_max_len: int, see `make_data_block`
+ :param add_eos_token: bool, see `make_data_block`
+ :param truncate_prompt: bool, see `make_data_block`
+ :param merge_prompt_label: bool, see `make_data_block`
+ :param load_fn_kwargs: Optional[dict], defaults to None, keyword arguments used
+ for `load_fn` or `datasets.load_dataset`
+ :param preprocess_fn_kwargs: Optional[dict], defaults to None, keyword arguments used
+ for `preprocess_fn`
+ :param kwargs: additional keyword arguments will be passed to torch's `DataLoader` initialization,
+ note values of `batch_size`, `shuffle` and `collate_fn` will always be overridden to fixed value
+ :return: torch.utils.data.DataLoader
+ """
+
+ if not load_fn_kwargs:
+ load_fn_kwargs = {}
+ if not preprocess_fn_kwargs:
+ preprocess_fn_kwargs = {}
+
+ if load_fn:
+ ds = load_fn(data_path_or_name, **load_fn_kwargs)
+ else:
+ ds = load_dataset(data_path_or_name, **load_fn_kwargs)
+ if isinstance(ds, (DatasetDict, IterableDatasetDict)):
+ if "evaluation" in ds:
+ ds = ds["evaluation"]
+ elif "test" in ds:
+ ds = ds["test"]
+ else:
+ ds = ds["train"]
+
+ ds = ds.select(
+ indices=random.sample(range(len(ds)), min(len(ds), num_samples)),
+ keep_in_memory=True,
+ )
+ ds = ds.map(
+ make_data_block,
+ batched=True,
+ batch_size=len(ds),
+ num_proc=1,
+ remove_columns=ds.column_names,
+ keep_in_memory=True,
+ load_from_cache_file=False,
+ fn_kwargs={
+ "prompt_col_name": prompt_col_name,
+ "label_col_name": label_col_name,
+ "tokenizer": tokenizer,
+ "preprocess_fn": partial(preprocess_fn, **preprocess_fn_kwargs),
+ "sample_max_len": sample_max_len,
+ "block_max_len": block_max_len,
+ "add_eos_token": add_eos_token,
+ "truncate_prompt": truncate_prompt,
+ "merge_prompt_label": merge_prompt_label,
+ },
+ )
+
+ # override some arguments' values in kwargs despite user specified
+ kwargs["batch_size"] = 1
+ kwargs["shuffle"] = False
+ kwargs["collate_fn"] = partial(collate_data, pad_token_id=tokenizer.pad_token_id)
+ dl = DataLoader(ds, **kwargs)
+
+ return dl
+
+
+__all__ = ["make_data_block", "collate_data", "get_dataloader"]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/exllama_utils.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/exllama_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..84b5da2fcad218e44edd9154046fa5f78903a5fb
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/exllama_utils.py
@@ -0,0 +1,79 @@
+import gc
+
+import torch
+
+from ..nn_modules.qlinear.qlinear_exllama import QuantLinear as ExllamaQuantLinear
+
+
+def exllama_set_max_input_length(model, max_input_length: int):
+ """
+ This method does not necessarily require `model` to inherit from BaseGPTQForCausalLM.
+
+ When using the exllama backend with act-order, it is necessary to initialize a buffer that depends on the maximum expected input length. In case the
+ default used (EXLLAMA_DEFAULT_MAX_INPUT_LENGTH) is too short, this method can be called to extend the buffer size without reloading the whole model.
+ """
+
+ # The import is set here to avoid a global import. Arguably this is quite ugly, it would be better to have lazy loading.
+ from exllama_kernels import cleanup_buffers_cuda, prepare_buffers
+
+ if not model.quantize_config.desc_act:
+ raise ValueError(
+ "The method exllama_set_max_input_length should be called only when using the exllama backend **with act-order**."
+ )
+
+ uses_exllama = False
+ for name, submodule in model.named_modules():
+ if isinstance(submodule, ExllamaQuantLinear):
+ uses_exllama = True
+
+ if not uses_exllama:
+ raise ValueError(
+ f"The function exllama_set_max_input_length was called, but the model (instance of {model.__class__.__name__}) does not use the exllama backend for GPTQ. An other implementation is used (exllamav2, cuda, cuda-old, triton) and that the call to exllama_set_max_input_length is unnecessary. Please remove the call to exllama_set_max_input_length or use the exllama v1 backend."
+ )
+
+ device_to_buffers_size = {}
+ for device, buffers in model.device_to_buffers.items():
+ device_to_buffers_size[device] = {
+ "max_dq_buffer_size": buffers["max_dq_buffer_size"],
+ "max_inner_outer_dim": buffers["max_inner_outer_dim"],
+ }
+
+ # For an unknown reason calling just `del model.device_to_buffers` raises an AttributeError.
+ for key in list(model.device_to_buffers.keys()):
+ del model.device_to_buffers[key]
+ model.device_to_buffers = None
+ del model.device_to_buffers
+
+ gc.collect()
+ torch.cuda.empty_cache()
+ cleanup_buffers_cuda()
+
+ device_to_buffers = {}
+ for device, buffers_size in device_to_buffers_size.items():
+ # The temp_state buffer is required to reorder X in the act-order case.
+ # The temp_dq buffer is required to dequantize weights when using cuBLAS, typically for the prefill.
+ device_to_buffers[device] = {
+ "temp_state": torch.zeros(
+ (max_input_length, buffers_size["max_inner_outer_dim"]),
+ dtype=torch.float16,
+ device=device,
+ ),
+ "temp_dq": torch.zeros(
+ (1, buffers_size["max_dq_buffer_size"]),
+ dtype=torch.float16,
+ device=device,
+ ),
+ "max_dq_buffer_size": buffers_size["max_dq_buffer_size"],
+ "max_inner_outer_dim": buffers_size["max_inner_outer_dim"],
+ }
+
+ prepare_buffers(
+ device,
+ device_to_buffers[device]["temp_state"],
+ device_to_buffers[device]["temp_dq"],
+ )
+
+ # Buffers need to be persistent to avoid any bug.
+ model.device_to_buffers = device_to_buffers
+
+ return model
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/import_utils.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/import_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..fe9aabf7db9aae5fc9d77437f0a7eec9c4f14c0b
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/import_utils.py
@@ -0,0 +1,121 @@
+from logging import getLogger
+from typing import Optional
+
+import torch
+from packaging.version import parse as parse_version
+
+
+try:
+ import triton # noqa: F401
+
+ TRITON_AVAILABLE = True
+except ImportError:
+ TRITON_AVAILABLE = False
+
+try:
+ import autogptq_cuda_64 # noqa: F401
+
+ AUTOGPTQ_CUDA_AVAILABLE = True
+except Exception:
+ AUTOGPTQ_CUDA_AVAILABLE = False
+
+
+try:
+ import exllama_kernels # noqa: F401
+
+ EXLLAMA_KERNELS_AVAILABLE = True
+except Exception:
+ EXLLAMA_KERNELS_AVAILABLE = False
+
+try:
+ import exllamav2_kernels # noqa: F401
+
+ EXLLAMAV2_KERNELS_AVAILABLE = True
+except Exception:
+ EXLLAMAV2_KERNELS_AVAILABLE = False
+
+try:
+ import cQIGen # noqa: F401
+
+ QIGEN_AVAILABLE = True
+ QIGEN_EXCEPTION = None
+except Exception as e:
+ QIGEN_AVAILABLE = False
+ QIGEN_EXCEPTION = e
+
+try:
+ import autogptq_marlin_cuda # noqa: F401
+
+ MARLIN_AVAILABLE = True
+ MARLIN_EXCEPTION = None
+except Exception as e:
+ MARLIN_AVAILABLE = False
+ MARLIN_EXCEPTION = e
+
+
+logger = getLogger(__name__)
+
+
+def dynamically_import_QuantLinear(
+ use_triton: bool,
+ desc_act: bool,
+ group_size: int,
+ bits: int,
+ disable_exllama: Optional[bool] = None,
+ disable_exllamav2: bool = False,
+ use_qigen: bool = False,
+ use_marlin: bool = False,
+ use_tritonv2: bool = False,
+):
+ if use_qigen:
+ if not QIGEN_AVAILABLE:
+ raise ValueError(
+ f"QIGen appears to be not available with the error: {QIGEN_EXCEPTION}. Please check your installation or use `use_qigen=False`."
+ )
+ from ..nn_modules.qlinear.qlinear_qigen import QuantLinear
+ else:
+ if use_triton or use_tritonv2:
+ if torch.version.hip:
+ logger.warning(
+ "Running GPTQ triton version on AMD GPUs is untested and may result in errors or wrong predictions. Please use use_triton=False."
+ )
+ if use_tritonv2:
+ logger.debug("Using tritonv2 for GPTQ")
+ from ..nn_modules.qlinear.qlinear_tritonv2 import QuantLinear
+ else:
+ from ..nn_modules.qlinear.qlinear_triton import QuantLinear
+ else:
+ # If disable_exllamav2 is True, we want to fall back on the exllama kernel and not the cuda/cuda_old ones.
+ if disable_exllama is None:
+ if disable_exllamav2:
+ disable_exllama = False
+ else:
+ disable_exllama = True
+ if bits == 4 and use_marlin:
+ from ..nn_modules.qlinear.qlinear_marlin import QuantLinear
+ elif bits == 4 and not disable_exllamav2 and EXLLAMAV2_KERNELS_AVAILABLE:
+ from ..nn_modules.qlinear.qlinear_exllamav2 import QuantLinear
+ elif bits == 4 and not disable_exllama and EXLLAMA_KERNELS_AVAILABLE:
+ from ..nn_modules.qlinear.qlinear_exllama import QuantLinear
+ elif not desc_act or group_size == -1:
+ from ..nn_modules.qlinear.qlinear_cuda_old import QuantLinear
+ else:
+ from ..nn_modules.qlinear.qlinear_cuda import QuantLinear
+
+ return QuantLinear
+
+
+def compare_transformers_version(version: str = "v4.28.0", op: str = "eq"):
+ assert op in ["eq", "lt", "le", "gt", "ge"]
+
+ from transformers import __version__
+
+ return getattr(parse_version(__version__), f"__{op}__")(parse_version(version))
+
+
+def compare_pytorch_version(version: str = "v2.0.0", op: str = "eq"):
+ assert op in ["eq", "lt", "le", "gt", "ge"]
+
+ from torch import __version__
+
+ return getattr(parse_version(__version__), f"__{op}__")(parse_version(version))
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/marlin_utils.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/marlin_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..61e1c62d7c9b78a3db0390771e020c34bb056d6a
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/marlin_utils.py
@@ -0,0 +1,211 @@
+import gc
+from logging import getLogger
+from typing import Tuple
+
+import torch
+from accelerate.utils import find_tied_parameters
+from safetensors.torch import save_file as safe_save
+from tqdm import tqdm
+
+from ..nn_modules.qlinear.qlinear_marlin import QuantLinear as MarlinQuantLinear
+from ..nn_modules.qlinear.qlinear_marlin import _get_perms, unpack_qzeros
+from ..quantization import CHECKPOINT_FORMAT, QUANT_METHOD, BaseQuantizeConfig
+from .accelerate_utils import load_checkpoint_in_model
+from .import_utils import MARLIN_AVAILABLE, MARLIN_EXCEPTION
+from .modeling_utils import recurse_getattr, recurse_setattr
+
+
+if MARLIN_AVAILABLE:
+ import autogptq_marlin_cuda
+
+logger = getLogger(__name__)
+
+
+def prepare_model_for_marlin_load(
+ model,
+ quantize_config: BaseQuantizeConfig,
+ quant_linear_class,
+ torch_dtype,
+ current_model_save_name,
+ device_map,
+):
+ # The model (e.g. model.safetensors) is already serialized in the Marlin format, load it directly.
+ if quantize_config.checkpoint_format == CHECKPOINT_FORMAT.MARLIN:
+ model_save_name = current_model_save_name
+ logger.info(f"Loading a GPTQ model, detected Marlin serialized format at {model_save_name}.")
+ model = convert_to_marlin(model, quant_linear_class, quantize_config, repack=False)
+ else:
+ model_save_name, is_cached = quantize_config.get_cache_file_path(quant_method=QUANT_METHOD.GPTQ,
+ checkpoint_format=CHECKPOINT_FORMAT.MARLIN)
+
+ # If GPTQ model has Marlin version cached locally, load from the cached version (no repacking needed).
+ if is_cached:
+ logger.info(
+ f"Loading a GPTQ model, detected a cached repacked weight for Marlin kernel at {model_save_name}."
+ )
+ model = convert_to_marlin(model, quant_linear_class, quantize_config, repack=False)
+
+ # Otherwise, convert the model to Marlin format first and cache locally.
+ else:
+ # Loading the GPTQ checkpoint to do the conversion.
+ # TODO: Avoid loading the model with wrong QuantLinear, and directly use
+ # Marlin ones. The repacking can be done directly on the safetensors, just
+ # as for AWQ checkpoints.
+ load_checkpoint_in_model(
+ model,
+ dtype=torch_dtype, # This is very hacky but works due to https://github.com/huggingface/accelerate/blob/bd72a5f1a80d5146554458823f8aeda0a9db5297/src/accelerate/utils/modeling.py#L292
+ checkpoint=current_model_save_name,
+ device_map=device_map,
+ offload_state_dict=True,
+ offload_buffers=True,
+ )
+ # Convert model to marlin, repacking weights into Marlin format.
+ model = convert_to_marlin(model, quant_linear_class, quantize_config, repack=True)
+
+ # Safetensors is unable to save tied weights, so we untie them here. Reference: https://github.com/huggingface/safetensors/issues/202
+ tied_params = find_tied_parameters(model)
+
+ for weight_group in tied_params:
+ for param_name in weight_group:
+ if isinstance(recurse_getattr(model, param_name), torch.nn.Parameter):
+ recurse_setattr(
+ model,
+ param_name,
+ torch.nn.Parameter(recurse_getattr(model, param_name).clone()),
+ )
+ else:
+ recurse_setattr(
+ model,
+ param_name,
+ recurse_getattr(model, param_name).clone(),
+ )
+
+ # Cache the converted model.
+ safe_save(model.state_dict(), model_save_name)
+
+ return model, model_save_name
+
+
+# Validate marlin support
+def _validate_marlin_device_support() -> Tuple[bool, bool]:
+ """
+ Validates if the current device is compatible and optimized for Marlin.
+ ref: https://github.com/IST-DASLab/marlin?tab=readme-ov-file#requirements
+
+ Returns:
+ Tuple[bool, bool]: The first indicates if CUDA device is compatible for Marlin,
+ the second indicates if CUDA device is optimized for Marlin.
+ """
+ supported = False
+ optimized = False
+
+ # >=hopper is compatible but not optimized
+ if torch.cuda.get_device_capability()[0] >= 9:
+ supported = True
+ optimized = False
+ # ampere and ada are supported and optimized
+ elif torch.cuda.get_device_capability()[0] >= 8:
+ supported = True
+ optimized = True
+
+ return supported, optimized
+
+
+# Adapted from https://github.com/rib-2/marlin/tree/conversion
+def _validate_marlin_compatibility(cfg: BaseQuantizeConfig):
+ if not MARLIN_AVAILABLE:
+ return f"AutoGPTQ is not compiled with the Marlin kernel, with the following error: {MARLIN_EXCEPTION}"
+ if cfg.bits != 4:
+ return f"The quantized model uses a bitwidth different than 4 (found {cfg.bits})"
+ if cfg.group_size != 128 and cfg.group_size != -1:
+ return "The quantized model uses a group size that is not 128 or -1 (found quantization_config.group_size)"
+ if not cfg.sym:
+ return "The quantized model uses asymmetric quantization"
+ if cfg.desc_act:
+ return "The quantized model uses act-order (also called desc-act) scheme"
+ if cfg.quant_method == QUANT_METHOD.AWQ:
+ return "awq_gemm format is currently not compatible with marlin"
+ return None
+
+
+@torch.no_grad()
+def convert_to_marlin(model, model_quantlinear, quantization_config: BaseQuantizeConfig, repack: bool, strict: bool = False):
+ """
+ Converts GPTQ-packed weights to the Marlin format. This assumes that the model already meets Marlin kernel constraints.
+
+ Arguments:
+ repack (`bool`):
+ Whether to repack the qweights from `model` into the Marlin's QuantLinear layers.
+ """
+ if repack:
+ message = "Repacking weights to be compatible with Marlin kernel..."
+ else:
+ # TODO: load directly Marlin QuantLinear.
+ message = "Overriding QuantLinear layers to use Marlin's QuantLinear..."
+
+ for name, module in tqdm(model.named_modules(), desc=message, total=len(list(model.named_modules()))):
+ if not isinstance(module, model_quantlinear):
+ continue
+
+ parent_name = ".".join(name.split(".")[:-1])
+ layer_name = name[len(parent_name) + 1 :]
+
+ # We could use `torch.count_nonzero(module.bias) > 0` here to discard zero bias, but this has issues when
+ # loading weights from checkpoints holding zero bias.
+ with torch.device("meta"):
+ new_module = MarlinQuantLinear(
+ bits=4,
+ group_size=module.group_size,
+ infeatures=module.infeatures,
+ outfeatures=module.outfeatures,
+ bias=module.bias is not None,
+ trainable=False,
+ )
+
+ # workspace is never in the state_dict, thus we need to allocate it manually.
+ new_module.workspace = torch.zeros(module.outfeatures // 128 * 16, dtype=torch.int, device=module.device)
+
+ # Dequantize the weight.
+ if repack:
+ marlin_repacked_weight = autogptq_marlin_cuda.gptq_repack(module.qweight)
+
+ if strict:
+ dequantized_qzeros = unpack_qzeros(module.qzeros)
+
+ if not torch.all(dequantized_qzeros == 8):
+ raise ValueError(
+ "Marlin kernel is compatible only with checkpoints using symmetric quantization."
+ "Found non-symmetric quantization for the weight {name}."
+ )
+
+
+ _, _scale_perm, _scale_perm_single = _get_perms()
+
+ s = module.scales.data.clone()
+ if module.group_size != module.infeatures:
+ s = s.reshape((1, -1))
+ s = s.reshape((-1, len(_scale_perm)))[:, _scale_perm]
+ else:
+ s = s.reshape((-1, len(_scale_perm_single)))[:, _scale_perm_single]
+ s = s.reshape((-1, module.outfeatures)).contiguous()
+
+ new_module.B = marlin_repacked_weight
+ new_module.s = s
+ new_module.bias = module.bias
+
+ new_module = new_module.to(module.device)
+
+ # Save to parent.
+ parent_module = model.get_submodule(parent_name)
+ setattr(parent_module, layer_name, new_module)
+
+ # Free cuda memory.
+ del module
+ if repack:
+ del marlin_repacked_weight
+ gc.collect()
+
+ # Set quantization config to be Marlin.
+ quantization_config.checkpoint_format = CHECKPOINT_FORMAT.MARLIN
+
+ return model
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/modeling_utils.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/modeling_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..bf298e957c1a39a0daa9c21a481c0b201f1e95d7
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/modeling_utils.py
@@ -0,0 +1,27 @@
+import functools
+
+
+def recurse_getattr(obj, attr: str):
+ """
+ Recursive `getattr`.
+
+ Args:
+ obj:
+ A class instance holding the attribute.
+ attr (`str`):
+ The attribute that is to be retrieved, e.g. 'attribute1.attribute2'.
+ """
+
+ def _getattr(obj, attr):
+ return getattr(obj, attr)
+
+ return functools.reduce(_getattr, [obj] + attr.split("."))
+
+
+def recurse_setattr(module, name, value):
+ """A function to recursively set attributes to a module."""
+ if "." not in name:
+ setattr(module, name, value)
+ else:
+ name, rest = name.split(".", 1)
+ recurse_setattr(getattr(module, name), rest, value)
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/peft_utils.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/peft_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..6030ba7419b211aa93e5ff5e495cbf92b0ab63a5
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/peft_utils.py
@@ -0,0 +1,421 @@
+import warnings
+from contextlib import contextmanager
+from typing import List, Optional, Tuple, Union
+
+import torch
+from peft import PeftConfig, PeftModel, PeftType, get_peft_model
+from peft.mapping import PEFT_TYPE_TO_CONFIG_MAPPING
+from peft.peft_model import PEFT_TYPE_TO_MODEL_MAPPING
+from peft.tuners.adalora import AdaLoraConfig, AdaLoraLayer, AdaLoraModel
+from peft.tuners.lora import LoraConfig, LoraLayer, LoraModel
+
+from ..modeling._base import BaseGPTQForCausalLM
+from ..nn_modules.qlinear import GeneralQuantLinear
+from ..nn_modules.qlinear.qlinear_cuda import QuantLinear as QuantLinearCuda
+from ..nn_modules.qlinear.qlinear_cuda_old import QuantLinear as QuantLinearCudaOld
+from ..nn_modules.qlinear.qlinear_exllama import QuantLinear as QuantLinearExllama
+from ..nn_modules.qlinear.qlinear_exllama import QuantLinear as QuantLinearExllamaV2
+from ..nn_modules.qlinear.qlinear_qigen import QuantLinear as QuantLinearQigen
+from ..nn_modules.qlinear.qlinear_triton import QuantLinear as QuantLinearTriton
+
+
+LinearLayer = Union[
+ torch.nn.Linear,
+ GeneralQuantLinear,
+ QuantLinearCuda,
+ QuantLinearCudaOld,
+ QuantLinearExllama,
+ QuantLinearExllamaV2,
+ QuantLinearQigen,
+ QuantLinearTriton,
+]
+
+
+class GPTQLoraConfig(LoraConfig):
+ injected_fused_attention: bool = False
+ injected_fused_mlp: bool = False
+
+
+def _get_linear_feature_count(linear_layer: LinearLayer) -> Tuple[int, int]:
+ in_features = getattr(linear_layer, "in_features", getattr(linear_layer, "infeatures"))
+ out_features = getattr(linear_layer, "out_features", getattr(linear_layer, "outfeatures"))
+ return in_features, out_features
+
+
+def _get_weight(linear_layer: LinearLayer) -> torch.Tensor:
+ return getattr(linear_layer, "weight", getattr(linear_layer, "qweight"))
+
+
+class GPTQLoraLinear(torch.nn.Linear, LoraLayer):
+ def __init__(
+ self,
+ adapter_name: str,
+ linear_module: LinearLayer,
+ r: int = 0,
+ lora_alpha: int = 1,
+ lora_dropout: float = 0.0,
+ fan_in_fan_out: bool = False, # Set this to True if the layer to replace stores weight like (fan_in, fan_out)
+ **kwargs,
+ ):
+ init_lora_weights = kwargs.pop("init_lora_weights", True)
+
+ in_features, out_features = _get_linear_feature_count(linear_module)
+ torch.nn.Linear.__init__(self, in_features, out_features)
+ LoraLayer.__init__(self, in_features, out_features)
+
+ self.linear_module = linear_module
+
+ delattr(self, "weight")
+ self.weight = _get_weight(linear_module)
+ delattr(self, "bias")
+
+ self.fan_in_fan_out = fan_in_fan_out
+ if fan_in_fan_out:
+ assert hasattr(linear_module, "weight")
+ linear_module.weight.data = linear_module.weight.data.T
+
+ self.update_layer(adapter_name, r, lora_alpha, lora_dropout, init_lora_weights)
+ self.active_adapter = adapter_name
+
+ def reset_lora_parameters(self, adapter_name):
+ if adapter_name in self.lora_A.keys():
+ torch.nn.init.xavier_uniform_(self.lora_A[adapter_name].weight)
+ torch.nn.init.zeros_(self.lora_B[adapter_name].weight)
+
+ def merge(self):
+ raise NotImplementedError("gptq model not support merge lora adapter")
+
+ def unmerge(self):
+ raise NotImplementedError("gptq model not support unmerge lora adapter")
+
+ def forward(self, x: torch.Tensor):
+ previous_dtype = x.dtype
+ if self.active_adapter not in self.lora_A.keys():
+ return self.linear_module(x)
+ if self.disable_adapters:
+ if self.r[self.active_adapter] > 0 and self.merged:
+ self.unmerge()
+ result = self.linear_module(x)
+ elif self.r[self.active_adapter] > 0 and not self.merged:
+ result = self.linear_module(x)
+
+ lora_B = self.lora_B[self.active_adapter]
+ lora_A = self.lora_A[self.active_adapter]
+ lora_dropout = self.lora_dropout[self.active_adapter]
+ scale = self.scaling[self.active_adapter]
+
+ x = x.type_as(lora_A.weight.data)
+ adapter_result = (lora_B(lora_A(lora_dropout(x))) * scale).type_as(result)
+ result += adapter_result
+ else:
+ result = self.linear_module(x)
+
+ result = result.to(previous_dtype)
+
+ return result
+
+
+class GPTQLoraModel(LoraModel):
+ def _replace_module(self, parent_module, child_name, new_module, old_module):
+ setattr(parent_module, child_name, new_module)
+ if not isinstance(new_module, GPTQLoraLinear):
+ new_module.weight = old_module.weight
+ if hasattr(old_module, "bias"):
+ if old_module.bias is not None:
+ new_module.bias = old_module.bias
+
+ if getattr(old_module, "state", None) is not None:
+ new_module.state = old_module.state
+ new_module.to(old_module.weight.device)
+
+ # dispatch to correct device
+ for name, module in new_module.named_modules():
+ if "lora_" in name:
+ device = (list(old_module.parameters()) + list(old_module.buffers()))[0].device
+ module.to(device)
+
+ @staticmethod
+ def _create_new_module(
+ lora_config: GPTQLoraConfig,
+ adapter_name: str,
+ target: torch.nn.Linear,
+ **kwargs,
+ ):
+ gptq_quantlinears = {
+ GeneralQuantLinear,
+ QuantLinearCuda,
+ QuantLinearCudaOld,
+ QuantLinearExllama,
+ QuantLinearExllamaV2,
+ QuantLinearQigen,
+ QuantLinearTriton,
+ }
+
+ is_gptq_layer = any(isinstance(target, cls) for cls in gptq_quantlinears)
+ if is_gptq_layer:
+ return GPTQLoraLinear(
+ adapter_name,
+ target,
+ r=lora_config.r,
+ lora_alpha=lora_config.lora_alpha,
+ lora_dropout=lora_config.lora_dropout,
+ fan_in_fan_out=lora_config.fan_in_fan_out,
+ )
+ else:
+ return LoraModel._create_new_module(lora_config, adapter_name, target, **kwargs)
+
+ def merge_adapter(self):
+ raise NotImplementedError("gptq model not support merge ada lora adapter")
+
+ def unmerge_adapter(self):
+ raise NotImplementedError("gptq model not support unmerge ada lora adapter")
+
+ def merge_and_unload(self):
+ raise NotImplementedError("gptq model not support merge and unload")
+
+
+class GPTQAdaLoraConfig(AdaLoraConfig):
+ injected_fused_attention: bool = False
+ injected_fused_mlp: bool = False
+
+
+class GPTQSVDLinear(torch.nn.Linear, AdaLoraLayer):
+ def __init__(
+ self,
+ adapter_name: str,
+ linear_module: LinearLayer,
+ r: int = 0,
+ lora_alpha: int = 1,
+ lora_dropout: float = 0.0,
+ fan_in_fan_out: bool = False, # Set this to True if the layer to replace stores weight like (fan_in, fan_out)
+ **kwargs,
+ ):
+ init_lora_weights = kwargs.pop("init_lora_weights", True)
+
+ in_features, out_features = _get_linear_feature_count(linear_module)
+ torch.nn.Linear.__init__(self, in_features, out_features)
+ AdaLoraLayer.__init__(self, in_features, out_features)
+
+ self.linear_module = linear_module
+
+ delattr(self, "weight")
+ self.weight = _get_weight(linear_module)
+ delattr(self, "bias")
+ self.fan_in_fan_out = fan_in_fan_out
+ if fan_in_fan_out:
+ assert hasattr(linear_module, "weight")
+ linear_module.weight.data = linear_module.weight.data.T
+
+ self.update_layer(adapter_name, r, lora_alpha, lora_dropout, init_lora_weights)
+ self.active_adapter = adapter_name
+
+ def merge(self):
+ raise NotImplementedError("gptq model not support merge lora adapter")
+
+ def unmerge(self):
+ raise NotImplementedError("gptq model not support unmerge lora adapter")
+
+ def forward(self, x: torch.Tensor):
+ if self.active_adapter not in self.lora_A.keys():
+ return self.linear_module(x)
+ if self.disable_adapters:
+ if self.r[self.active_adapter] > 0 and self.merged:
+ self.unmerge()
+ result = self.linear_module(x)
+ elif self.r[self.active_adapter] > 0 and not self.merged:
+ result = self.linear_module(x)
+ result += (
+ (
+ self.lora_dropout[self.active_adapter](x)
+ @ (self.lora_A[self.active_adapter] * self.lora_E[self.active_adapter]).T
+ @ self.lora_B[self.active_adapter].T
+ )
+ * self.scaling[self.active_adapter]
+ / (self.ranknum[self.active_adapter] + 1e-5)
+ )
+ else:
+ result = self.linear_module(x)
+ return result
+
+ def reset_lora_parameters(self, adapter_name):
+ if adapter_name in self.lora_A.keys():
+ # Peft standard values seems too high
+ # Still not ideal, just not causing NaNs with fp16 anymore
+ torch.nn.init.normal_(self.lora_E[adapter_name], mean=0.0, std=0.005)
+ torch.clamp_(self.lora_E[adapter_name].data, -0.1, 0.1)
+ torch.nn.init.normal_(self.lora_A[adapter_name], mean=0.0, std=0.005)
+ torch.clamp_(self.lora_A[adapter_name].data, -0.1, 0.1)
+ torch.nn.init.normal_(self.lora_B[adapter_name], mean=0.0, std=0.005)
+ torch.clamp_(self.lora_B[adapter_name].data, -0.1, 0.1)
+
+
+class GPTQAdaLoraModel(AdaLoraModel):
+ def _replace_module(self, parent_module, child_name, new_module, old_module):
+ setattr(parent_module, child_name, new_module)
+
+ # dispatch to correct device
+ for name, module in new_module.named_modules():
+ if "lora_" in name:
+ device = (list(old_module.parameters()) + list(old_module.buffers()))[0].device
+ module.to(device)
+
+ @staticmethod
+ def _create_new_module(
+ lora_config: GPTQLoraConfig,
+ adapter_name: str,
+ target: torch.nn.Linear,
+ **kwargs,
+ ):
+ gptq_quantlinears = {
+ GeneralQuantLinear,
+ QuantLinearCuda,
+ QuantLinearCudaOld,
+ QuantLinearExllama,
+ QuantLinearExllamaV2,
+ QuantLinearQigen,
+ QuantLinearTriton,
+ }
+
+ is_gptq_layer = any(isinstance(target, cls) for cls in gptq_quantlinears)
+ if is_gptq_layer:
+ return GPTQSVDLinear(
+ adapter_name,
+ target,
+ r=lora_config.r,
+ lora_alpha=lora_config.lora_alpha,
+ lora_dropout=lora_config.lora_dropout,
+ fan_in_fan_out=lora_config.fan_in_fan_out,
+ )
+ else:
+ return LoraModel._create_new_module(lora_config, adapter_name, target, **kwargs)
+
+ def merge_adapter(self):
+ raise NotImplementedError("gptq model not support merge ada lora adapter")
+
+ def unmerge_adapter(self):
+ raise NotImplementedError("gptq model not support unmerge ada lora adapter")
+
+ def merge_and_unload(self):
+ raise NotImplementedError("gptq model not support merge and unload")
+
+
+def find_all_linear_names(
+ model: BaseGPTQForCausalLM,
+ ignore: Optional[List[str]] = None,
+ ignore_lm_head: bool = True,
+):
+ if not ignore:
+ ignore = []
+ lm_head_name = model.lm_head_name
+ if ignore_lm_head and lm_head_name not in ignore:
+ ignore.append(lm_head_name)
+ results = set()
+ for n, m in model.named_modules():
+ if isinstance(m, torch.nn.Linear):
+ res = n.split(".")[-1]
+ if res not in ignore:
+ results.add(res)
+ return list(results)
+
+
+@contextmanager
+def hijack_peft_mappings():
+ PEFT_TYPE_TO_CONFIG_MAPPING[PeftType.LORA] = GPTQLoraConfig
+ PEFT_TYPE_TO_MODEL_MAPPING[PeftType.LORA] = GPTQLoraModel
+ PEFT_TYPE_TO_CONFIG_MAPPING[PeftType.ADALORA] = GPTQAdaLoraConfig
+ PEFT_TYPE_TO_MODEL_MAPPING[PeftType.ADALORA] = GPTQAdaLoraModel
+
+ try:
+ yield
+ except:
+ PEFT_TYPE_TO_CONFIG_MAPPING[PeftType.LORA] = GPTQLoraConfig
+ PEFT_TYPE_TO_MODEL_MAPPING[PeftType.LORA] = GPTQLoraModel
+ PEFT_TYPE_TO_CONFIG_MAPPING[PeftType.ADALORA] = GPTQAdaLoraConfig
+ PEFT_TYPE_TO_MODEL_MAPPING[PeftType.ADALORA] = GPTQAdaLoraModel
+ raise
+ finally:
+ PEFT_TYPE_TO_CONFIG_MAPPING[PeftType.LORA] = GPTQLoraConfig
+ PEFT_TYPE_TO_MODEL_MAPPING[PeftType.LORA] = GPTQLoraModel
+ PEFT_TYPE_TO_CONFIG_MAPPING[PeftType.ADALORA] = GPTQAdaLoraConfig
+ PEFT_TYPE_TO_MODEL_MAPPING[PeftType.ADALORA] = GPTQAdaLoraModel
+
+
+def get_gptq_peft_model(
+ model: BaseGPTQForCausalLM,
+ peft_config: PeftConfig = None,
+ model_id: str = None,
+ adapter_name: str = "default",
+ auto_find_all_linears: bool = True,
+ train_mode: bool = False,
+):
+ if train_mode and not model.trainable:
+ model.enable_trainable_mode()
+ if train_mode and not peft_config:
+ raise ValueError("peft_config not specified when in train mode.")
+ if not train_mode and not model_id:
+ raise ValueError("model_id(where to load adapters) not specified when in inference mode.")
+
+ if model.fused_attn_module_type is not None and not model.injected_fused_attention:
+ peft_types = [PeftType.LORA.value, PeftType.ADALORA.value]
+ warnings.warn(
+ f"You can just ignore this warning if the peft type you use isn't in {peft_types}.\n"
+ f"{model.__class__.__name__} supports injecting fused attention but not enables this time. "
+ "If you are training adapters, you must also disable fused attention injection when loading quantized "
+ "base model at inference time, otherwise adapters may not be added to base model properly. "
+ "If you are loading adapters to do inference, you can reference to adapter's config file to check "
+ "whether the adapters are trained using base model that not enable fused attention injection."
+ )
+ if model.injected_fused_mlp:
+ raise NotImplementedError(
+ "GPTQ model that enables fused mlp injection is not supported to integrate with peft."
+ )
+
+ if train_mode:
+ peft_type = peft_config.peft_type
+ if not isinstance(peft_type, str):
+ peft_type = peft_type.value
+ if peft_type in [PeftType.LORA.value, PeftType.ADALORA.value]:
+ if auto_find_all_linears:
+ peft_config.target_modules = find_all_linear_names(model, ignore_lm_head=True)
+ if peft_type == PeftType.LORA.value and not isinstance(peft_config, GPTQLoraConfig):
+ peft_config = GPTQLoraConfig(**peft_config.to_dict())
+ if peft_type == PeftType.ADALORA.value and not isinstance(peft_config, GPTQAdaLoraConfig):
+ peft_config = GPTQAdaLoraConfig(**peft_config.to_dict())
+ peft_config.injected_fused_attention = model.injected_fused_attention
+ peft_config.injected_fused_mlp = model.injected_fused_mlp
+ if peft_type == PeftType.ADAPTION_PROMPT.value:
+ if peft_config.adapter_layers > model.config.num_hidden_layers:
+ warnings.warn(
+ f"model has only {model.config.num_hidden_layers} layers "
+ f"but adapter_layers is set to {peft_config.adapter_layers}, "
+ f"will reset value to {model.config.num_hidden_layers}."
+ )
+ peft_config.adapter_layers = model.config.num_hidden_layers
+ if model.injected_fused_attention:
+ raise NotImplementedError(
+ "model with fused attention injected isn't supported to use ADAPTION_PROMPT peft type yet."
+ )
+
+ with hijack_peft_mappings():
+ try:
+ if train_mode:
+ peft_model = get_peft_model(model.model, peft_config, adapter_name=adapter_name)
+ else:
+ peft_model = PeftModel.from_pretrained(model.model, model_id, adapter_name)
+ except:
+ raise
+ raise NotImplementedError(
+ f"{model.__class__.__name__} not support {peft_config.peft_type.value} peft type yet."
+ )
+
+ return peft_model
+
+
+__all__ = [
+ "GPTQLoraConfig",
+ "GPTQLoraModel",
+ "GPTQAdaLoraConfig",
+ "GPTQAdaLoraModel",
+ "find_all_linear_names",
+ "get_gptq_peft_model",
+]
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/perplexity_utils.py b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/perplexity_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..2d9f103469f4c5e6c115907b7cbdea101a10ead7
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/auto_gptq/utils/perplexity_utils.py
@@ -0,0 +1,223 @@
+import sys
+
+import numpy as np
+import torch
+from datasets import load_dataset
+from tqdm import tqdm
+
+
+class Perplexity:
+ """
+ A class for calculating the perplexity of a language model.
+ """
+
+ def __init__(
+ self,
+ model,
+ tokenizer,
+ dataset_path="wikitext",
+ dataset_name=None,
+ split="test",
+ text_column="text",
+ ):
+ """
+ Calculate perplexity using the same method as seen in llama.cpp.
+
+ Parameters
+ ----------
+ model : AutoModelForCausalLM
+ The language model for which the perplexity is calculated.
+ tokenizer : AutoTokenizer
+ The tokenizer corresponding to the model.
+ device : str, optional
+ The device to run the calculations on. If auto, the device that your model uses
+ will be the device used for these calculations. Default is 'auto'.
+ dataset_path : str, optional
+ The path to the dataset on the Hugging Face dataset hub. Default is 'wikitext'.
+ dataset_name : str, optional
+ The name of the dataset. Default is None.
+ split : str, optional
+ The split of the dataset to use. Default is 'test'.
+ text_column : str, optional
+ The name of the column in the dataset that contains the text data. Default is 'text'.
+ """
+ self._model = model
+ self._tokenizer = tokenizer
+ self._dataset_path = dataset_path
+ self._dataset_name = dataset_name
+ self._split = split
+ self._text_column = text_column
+ self._text = self._prepare_data()
+
+ def _get_device(self):
+ if torch.backends.mps.is_available():
+ return "mps"
+ elif torch.cuda.is_available():
+ return "cuda:0"
+ else:
+ return "cpu"
+
+ def _prepare_data(self):
+ """
+ Prepares the dataset by loading and formatting.
+
+ Returns
+ -------
+ str
+ The formatted dataset as a single string.
+ """
+ if self._dataset_path == "wikitext":
+ self._dataset_name = "wikitext-2-raw-v1"
+
+ # Load the dataset
+ data = load_dataset(self._dataset_path, self._dataset_name, split=self._split)
+ # Format the text column of the dataset
+ text_list = [" \n" if s == "" else s for s in data[self._text_column]]
+ return "".join(text_list)
+
+ @staticmethod
+ def softmax(logits):
+ """
+ Static method for applying the softmax function.
+
+ Parameters
+ ----------
+ logits : np.ndarray
+ The input to the softmax function.
+
+ Returns
+ -------
+ np.ndarray
+ The output of the softmax function.
+ """
+ e_x = np.exp(logits - np.max(logits))
+ return e_x / e_x.sum(axis=0)
+
+ def calculate_perplexity(self, n_ctx=512, n_batch=512):
+ """
+ Calculates the perplexity of the language model.
+
+ Parameters
+ ----------
+ n_ctx : int
+ The context size.
+ n_batch : int
+ The batch size.
+
+ Returns
+ -------
+ list
+ The list of perplexity scores calculated.
+ """
+ # Tokenize the text
+ self._tokenizer.model_max_length = sys.maxsize
+ tokens = self._tokenizer(self._text, truncation=False, return_tensors="pt").input_ids.to(self._model.device)
+
+ nll = 0.0 # Negative log likelihood
+ count = 0 # Counter for processed tokens
+ curr_ppl = 0
+ all_perplexity = []
+
+ with tqdm(range(len(tokens[0]) // n_ctx), desc="Perplexity: - ") as progress:
+ for i in progress:
+ # Process each batch of tokens
+ nll, count = self._process_batch(i, n_ctx, n_batch, tokens, nll, count)
+
+ # Calculate and display the current perplexity
+ curr_ppl = np.exp(nll / count)
+ all_perplexity.append(curr_ppl)
+ progress.set_description(f"Perplexity: {curr_ppl:.4f}")
+
+ return all_perplexity
+
+ def _process_batch(self, i, n_ctx, n_batch, tokens, nll, count):
+ """
+ Processes each batch of tokens.
+
+ Parameters
+ ----------
+ i : int
+ The batch index.
+ n_ctx : int
+ The context size.
+ n_batch : int
+ The batch size.
+ tokens : torch.Tensor
+ The tokenized text.
+ nll : float
+ The current negative log likelihood.
+ count : int
+ The current count of processed tokens.
+
+ Returns
+ -------
+ float
+ The updated negative log likelihood.
+ int
+ The updated count of processed tokens.
+ """
+ start = i * n_ctx
+ end = start + n_ctx
+
+ num_batches = (n_ctx + n_batch - 1) // n_batch
+
+ logits = []
+
+ for j in range(num_batches):
+ batch_start = start + j * n_batch
+ batch_size = min(end - batch_start, n_batch)
+
+ token_org = tokens[0][batch_start].item()
+
+ if j == 0:
+ # Replace the first token with the BOS token
+ tokens[0][batch_start] = self._tokenizer.bos_token_id
+
+ # Compute the logits for the current batch of tokens
+ batch_logits = self._compute_batch_logits(tokens, batch_start, batch_size)
+
+ tokens[0][batch_start] = token_org
+
+ logits.append(batch_logits)
+
+ # We rely on the fact that attention in the forward pass only looks at previous
+ # tokens here, so the logits returned for each token are an accurate representation
+ # of what the model would have predicted at that point.
+ #
+ # Example, we have a context window of 512, we will compute perplexity for each of the
+ # last 256 tokens. Then, we split the input up into context window size chunks to
+ # process the entire prompt.
+
+ for j in range(min(512, n_ctx // 2), n_ctx - 1):
+ tok_logits = logits[0][0][j].cpu().numpy()
+ # Compute the probability of the next token
+ prob = self.softmax(tok_logits)[tokens[0][start + j + 1]]
+
+ # Update the negative log likelihood and the count of processed tokens
+ nll += -np.log(prob, where=prob > 0)
+ count += 1
+
+ return nll, count
+
+ def _compute_batch_logits(self, tokens, batch_start, batch_size):
+ """
+ Computes the logits for a batch of tokens.
+
+ Parameters
+ ----------
+ tokens : torch.Tensor
+ The tokenized text.
+ batch_start : int
+ The start index of the batch.
+ batch_size : int
+ The size of the batch.
+
+ Returns
+ -------
+ torch.Tensor
+ The logits for the batch of tokens.
+ """
+ # Compute the logits without keeping track of gradients
+ with torch.no_grad():
+ outputs = self._model(tokens[:, batch_start : batch_start + batch_size])
+ return outputs.logits.detach()
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/cuda_256/autogptq_cuda_256.cpp b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/cuda_256/autogptq_cuda_256.cpp
new file mode 100644
index 0000000000000000000000000000000000000000..dad762e6e5a0da0a8e9704b97c6ddfe113f8e183
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/cuda_256/autogptq_cuda_256.cpp
@@ -0,0 +1,187 @@
+#include
+#include
+#include
+
+void vecquant2matmul_cuda(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+);
+
+void vecquant2matmul(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant2matmul_cuda(vec, mat, mul, scales, zeros, g_idx);
+}
+
+void vecquant3matmul_cuda(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+);
+
+void vecquant3matmul(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant3matmul_cuda(vec, mat, mul, scales, zeros, g_idx);
+}
+
+void vecquant4matmul_cuda(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+);
+
+void vecquant4matmul(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant4matmul_cuda(vec, mat, mul, scales, zeros, g_idx);
+}
+
+void vecquant8matmul_cuda(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+);
+
+void vecquant8matmul(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant8matmul_cuda(vec, mat, mul, scales, zeros, g_idx);
+}
+
+
+// old
+
+void vecquant2matmul_cuda_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+);
+
+void vecquant2matmul_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant2matmul_cuda_old(vec, mat, mul, scales, zeros,groupsize);
+}
+
+void vecquant3matmul_cuda_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+);
+
+void vecquant3matmul_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant3matmul_cuda_old(vec, mat, mul, scales, zeros, groupsize);
+}
+
+void vecquant4matmul_cuda_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+);
+
+void vecquant4matmul_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant4matmul_cuda_old(vec, mat, mul, scales, zeros, groupsize);
+}
+
+void vecquant8matmul_cuda_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+);
+
+void vecquant8matmul_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant8matmul_cuda_old(vec, mat, mul, scales, zeros, groupsize);
+}
+
+void vecquant2matmul_faster_cuda_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize, int vec_height
+);
+
+void vecquant2matmul_faster_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize, int vec_height
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant2matmul_faster_cuda_old(vec, mat, mul, scales, zeros, groupsize, vec_height);
+}
+
+void vecquant3matmul_faster_cuda_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize, int vec_height
+);
+
+void vecquant3matmul_faster_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize, int vec_height
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant3matmul_faster_cuda_old(vec, mat, mul, scales, zeros, groupsize, vec_height);
+}
+
+void vecquant4matmul_faster_cuda_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize, int vec_height
+);
+
+void vecquant4matmul_faster_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize, int vec_height
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant4matmul_faster_cuda_old(vec, mat, mul, scales, zeros, groupsize, vec_height);
+}
+
+
+PYBIND11_MODULE(TORCH_EXTENSION_NAME, m) {
+ m.def("vecquant2matmul", &vecquant2matmul, "Vector 2-bit Quantized Matrix Multiplication (CUDA) (desc_act)");
+ m.def("vecquant3matmul", &vecquant3matmul, "Vector 3-bit Quantized Matrix Multiplication (CUDA) (desc_act)");
+ m.def("vecquant4matmul", &vecquant4matmul, "Vector 4-bit Quantized Matrix Multiplication (CUDA) (desc_act)");
+ m.def("vecquant8matmul", &vecquant8matmul, "Vector 8-bit Quantized Matrix Multiplication (CUDA) (desc_act)");
+
+ m.def("vecquant2matmul_old", &vecquant2matmul_old, "Vector 2-bit Quantized Matrix Multiplication (CUDA)");
+ m.def("vecquant3matmul_old", &vecquant3matmul_old, "Vector 3-bit Quantized Matrix Multiplication (CUDA)");
+ m.def("vecquant4matmul_old", &vecquant4matmul_old, "Vector 4-bit Quantized Matrix Multiplication (CUDA)");
+ m.def("vecquant8matmul_old", &vecquant8matmul_old, "Vector 8-bit Quantized Matrix Multiplication (CUDA)");
+ m.def("vecquant2matmul_faster_old", &vecquant2matmul_faster_old, "Vector 2-bit Quantized Matrix Multiplication (CUDA), faster version");
+ m.def("vecquant3matmul_faster_old", &vecquant3matmul_faster_old, "Vector 3-bit Quantized Matrix Multiplication (CUDA), faster version");
+ m.def("vecquant4matmul_faster_old", &vecquant4matmul_faster_old, "Vector 4-bit Quantized Matrix Multiplication (CUDA), faster version");
+}
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/cuda_256/autogptq_cuda_kernel_256.cu b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/cuda_256/autogptq_cuda_kernel_256.cu
new file mode 100644
index 0000000000000000000000000000000000000000..9768f3d1b4cbc99a26e019b5d4d0fb7e75ba4b14
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/cuda_256/autogptq_cuda_kernel_256.cu
@@ -0,0 +1,1437 @@
+#include
+#include
+#include
+#include
+#include
+
+// atomicAdd for double-precision floating-point numbers on hardware with
+// compute capability < 6.0 from:
+// https://docs.nvidia.com/cuda/cuda-c-programming-guide/index.html#atomic-functions
+// #if defined(__CUDA_ARCH__) && __CUDA_ARCH__ < 600
+// __device__ double atomicAdd(
+// double* address,
+// double val
+// ) {
+// unsigned long long int* address_as_ull = (unsigned long long int*)address;
+// unsigned long long int old = *address_as_ull, assumed;
+//
+// do {
+// assumed = old;
+// old = atomicCAS(
+// address_as_ull,
+// assumed,
+// __double_as_longlong(val + __longlong_as_double(assumed))
+// );
+//
+// // Note: uses integer comparison to avoid hang in case of NaN (since NaN != NaN)
+// } while (assumed != old);
+//
+// return __longlong_as_double(old);
+// }
+// #endif
+
+#if (defined(__CUDA_ARCH__) && __CUDA_ARCH__ < 700) || defined(USE_ROCM)
+// adapted from https://github.com/torch/cutorch/blob/master/lib/THC/THCAtomics.cuh
+
+__device__ __forceinline__ void atomicAdd(c10::Half* address, c10::Half val) {
+ unsigned int *address_as_ui = reinterpret_cast(reinterpret_cast(address) - (reinterpret_cast(address) & 2));
+ unsigned int old = *address_as_ui;
+ unsigned int assumed;
+
+ do {
+ assumed = old;
+ unsigned short hsum = reinterpret_cast(address) & 2 ? (old >> 16) : (old & 0xffff);
+ hsum += val;
+ old = reinterpret_cast(address) & 2
+ ? (old & 0xffff) | (hsum << 16)
+ : (old & 0xffff0000) | hsum;
+ old = atomicCAS(address_as_ui, assumed, old);
+
+ // Note: uses integer comparison to avoid hang in case of NaN (since NaN != NaN)
+ } while (assumed != old);
+}
+__device__ __forceinline__ void atomicAdd(__half* address, c10::Half val) {
+ unsigned int * address_as_ui = (unsigned int *) ((char *)address - ((size_t)address & 2));
+ unsigned int old = *address_as_ui;
+ unsigned int assumed;
+
+ do {
+ assumed = old;
+ __half_raw hsum;
+ hsum.x = (size_t)address & 2 ? (old >> 16) : (old & 0xffff);
+ half tmpres = __hadd(hsum, val);
+ hsum = __half_raw(tmpres);
+ old = (size_t)address & 2 ? (old & 0xffff) | (hsum.x << 16) : (old & 0xffff0000) | hsum.x;
+ old = atomicCAS(address_as_ui, assumed, old);
+ } while (assumed != old);
+}
+#endif
+
+
+template
+__global__ void VecQuant2MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+);
+
+template
+__global__ void VecQuant3MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+);
+
+template
+__global__ void VecQuant4MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+);
+
+template
+__global__ void VecQuant8MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+);
+
+template
+__global__ void VecQuant2MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+);
+
+template
+__global__ void VecQuant3MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+);
+
+template
+__global__ void VecQuant4MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+);
+
+template
+__global__ void VecQuant8MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+);
+
+__global__ void VecQuant2MatMulKernelFaster_old(
+ const half2* __restrict__ vec,
+ const int* __restrict__ mat,
+ float* __restrict__ mul,
+ const float* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+);
+
+__global__ void VecQuant3MatMulKernelFaster_old(
+ const half2* __restrict__ vec,
+ const int* __restrict__ mat,
+ float* __restrict__ mul,
+ const float* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+);
+
+__global__ void VecQuant4MatMulKernelFaster_old(
+ const half2* __restrict__ vec,
+ const int* __restrict__ mat,
+ float* __restrict__ mul,
+ const float* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+);
+
+
+const int BLOCKWIDTH = 256;
+const int BLOCKHEIGHT2 = 16;
+const int BLOCKHEIGHT3 = 24;
+const int BLOCKHEIGHT4 = 32;
+const int BLOCKHEIGHT8 = 64;
+
+__device__ inline unsigned int as_unsigned(int i) {
+ return *reinterpret_cast(&i);
+}
+
+__device__ inline int as_int(int i) {
+ return *reinterpret_cast(&i);
+}
+
+
+void vecquant2matmul_cuda(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT2 - 1) / BLOCKHEIGHT2,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant2matmul_cuda", ([&] {
+ VecQuant2MatMulKernel<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(), g_idx.data(),
+ batch, vec_height, height, width, zero_width
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant2MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+) {
+ int h = BLOCKHEIGHT2 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ int i = width * h + w;
+ int g_h = h * 16;
+ int k;
+ unsigned int g;
+ scalar_t w_tmp;
+
+ int z_w = w / 16;
+ int z_mod = (w % 16) * 2;
+
+ float weight[BLOCKWIDTH];
+
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ int k_w = (k / 16);
+ int k_bit = (k % 16) * 2;
+
+ g = as_int(g_idx[g_h + k]);
+ scalar_t scale = scales[g * width + w];
+
+ // Avoid overflows with & 0x0f.
+ scalar_t zero = scalar_t(((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod & 0x3) + 1) & 0x0f);
+
+ w_tmp = ((as_unsigned(mat[i + (k_w * width)]) >> k_bit) & 0x3);
+
+ weight[k] = scale * (w_tmp - zero);
+ }
+
+ scalar_t res;
+ for (int b = 0; b < batch; ++b){
+ res = 0;
+
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ res += weight[k] * blockvec[k];
+ }
+ atomicAdd(&mul[b * width + w], res);
+ __syncthreads();
+ }
+}
+
+void vecquant3matmul_cuda(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT3 - 1) / BLOCKHEIGHT3,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant3matmul_cuda", ([&] {
+ VecQuant3MatMulKernel<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(), g_idx.data(),
+ batch, vec_height, height, width, zero_width
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant3MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+) {
+ int h = BLOCKHEIGHT3 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ int i = width * h + w;
+ int g_h = (h / 3) * 32;
+ int k;
+ unsigned int g;
+ scalar_t w_tmp;
+
+ int z_w = (w / 32) * 3;
+ int z_mod = w % 32;
+ int z_bit;
+ unsigned int z_tmp;
+ if (z_mod != 10){
+ if (z_mod != 21){
+ z_bit = z_mod;
+ if (z_bit > 21){
+ z_bit -= 22;
+ z_bit *= 3;
+ z_bit += 2;
+ z_w += 2;
+ } else if (z_bit > 10){
+ z_bit -= 11;
+ z_bit *= 3;
+ z_bit += 1;
+ z_w += 1;
+ } else {
+ z_bit *= 3;
+ }
+ } else {
+ z_w += 1;
+ }
+ }
+
+ float weight[BLOCKWIDTH];
+
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ int k_w = (k / 32) * 3;
+ int k_mod = k % 32;
+ int k_bit;
+
+ if (k_mod != 10){
+ if (k_mod != 21){
+ k_bit = k_mod;
+ if (k_bit > 21){
+ k_bit -= 22;
+ k_bit *= 3;
+ k_bit += 2;
+ k_w += 2;
+ } else if (k_bit > 10){
+ k_bit -= 11;
+ k_bit *= 3;
+ k_bit += 1;
+ k_w += 1;
+ } else {
+ k_bit *= 3;
+ }
+ } else {
+ k_w += 1;
+ }
+ }
+
+ g = as_int(g_idx[g_h + k]);
+ scalar_t scale = scales[g * width + w];
+ scalar_t zero;
+ if (z_mod == 10) {
+ z_tmp = (as_unsigned(zeros[g * zero_width + z_w]) >> 30) | ((as_unsigned(zeros[g * zero_width + (z_w + 1)]) << 2) & 0x4);
+ zero = scalar_t(((z_tmp) + 1) & 0x0f); // Avoid overflows
+ } else if (z_mod == 21){
+ z_tmp = (as_unsigned(zeros[g * zero_width + z_w]) >> 31) | ((as_unsigned(zeros[g * zero_width + (z_w + 1)]) << 1) & 0x6);
+ zero = scalar_t(((z_tmp) + 1) & 0x0f);
+ } else {
+ zero = scalar_t((((as_unsigned(zeros[g * zero_width + z_w]) >> z_bit) & 0x7) + 1) & 0x0f);
+ }
+
+ if (k_mod == 10) {
+ w_tmp = (as_unsigned(mat[i + (k_w * width)]) >> 30) | ((as_unsigned(mat[i + ((k_w + 1)* width)]) << 2) & 0x4);
+ } else if (k_mod == 21){
+ w_tmp = (as_unsigned(mat[i + (k_w * width)]) >> 31) | ((as_unsigned(mat[i + ((k_w + 1)* width)]) << 1) & 0x6);
+ } else {
+ w_tmp = ((as_unsigned(mat[i + (k_w * width)]) >> k_bit) & 0x7);
+ }
+ weight[k] = scale * (w_tmp - zero);
+ }
+
+ scalar_t res;
+ for (int b = 0; b < batch; ++b){
+ res = 0;
+
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ res += weight[k] * blockvec[k];
+ }
+ atomicAdd(&mul[b * width + w], res);
+ __syncthreads();
+ }
+}
+
+void vecquant4matmul_cuda(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT4 - 1) / BLOCKHEIGHT4,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant4matmul_cuda", ([&] {
+ VecQuant4MatMulKernel<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(), g_idx.data(),
+ batch, vec_height, height, width, zero_width
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant4MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+) {
+ int h = BLOCKHEIGHT4 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ int i = width * h + w;
+ int g_h = h * 8;
+ int k;
+ unsigned int g;
+ scalar_t w_tmp;
+
+
+ int z_w = w / 8;
+ int z_mod = (w % 8) * 4;
+
+ float weight[BLOCKWIDTH];
+
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ int k_w = (k / 8);
+ int k_bit = (k % 8) * 4;
+
+ g = as_int(g_idx[g_h + k]);
+ scalar_t scale = scales[g * width + w];
+ scalar_t zero = scalar_t((((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod) & 0xF) + 1) & 0x0f);
+
+ w_tmp = ((as_unsigned(mat[i + (k_w * width)]) >> k_bit) & 0xF);
+
+ weight[k] = scale * (w_tmp - zero);
+ }
+
+ scalar_t res;
+ for (int b = 0; b < batch; ++b){
+ res = 0;
+
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ res += weight[k] * blockvec[k];
+ }
+ atomicAdd(&mul[b * width + w], res);
+ __syncthreads();
+ }
+}
+
+void vecquant8matmul_cuda(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT8 - 1) / BLOCKHEIGHT8,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant8matmul_cuda", ([&] {
+ VecQuant8MatMulKernel<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(), g_idx.data(),
+ batch, vec_height, height, width, zero_width
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant8MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+) {
+ int h = BLOCKHEIGHT8 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ int i = width * h + w;
+ int g_h = h * 4;
+ int k;
+ unsigned int g;
+ scalar_t w_tmp;
+
+ int z_w = w / 4;
+ int z_mod = (w % 4) * 8;
+
+ float weight[BLOCKWIDTH];
+
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ int k_w = (k / 4);
+ int k_bit = (k % 4) * 8;
+
+ g = as_int(g_idx[g_h + k]);
+ scalar_t scale = scales[g * width + w];
+ scalar_t zero = scalar_t((((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod) & 0xFF) + 1) & 0x0f);
+
+ w_tmp = ((as_unsigned(mat[i + (k_w * width)]) >> k_bit) & 0xFF);
+
+ weight[k] = scale * (w_tmp - zero);
+ }
+
+ scalar_t res;
+ for (int b = 0; b < batch; ++b){
+ res = 0;
+
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ res += weight[k] * blockvec[k];
+ }
+ atomicAdd(&mul[b * width + w], res);
+ __syncthreads();
+ }
+}
+
+
+void vecquant2matmul_cuda_old(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ int groupsize
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT2 - 1) / BLOCKHEIGHT2,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH,
+ batch
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant2matmul_cuda_old", ([&] {
+ VecQuant2MatMulKernel_old<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(),
+ batch, vec_height, height, width, zero_width, groupsize
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant2MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+) {
+ int b = blockIdx.z;
+ int h = BLOCKHEIGHT2 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+
+ scalar_t res = 0;
+ int i = width * h + w;
+ int g_h = h * 16;
+ int k = 0;
+
+ int z_w = w / 16;
+ int z_mod = (w % 16) * 2;
+
+ unsigned int tmp;
+
+ while (k < BLOCKWIDTH) {
+ tmp = as_unsigned(mat[i]);
+
+ int g = (g_h + k) / groupsize;
+ scalar_t scale = scales[g * width + w];
+ scalar_t zero = scale * scalar_t(((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod & 0x3) + 1) & 0x0f);
+
+ res += (scale * scalar_t((tmp >> 0) & 0x3) - zero) * blockvec[k + 0];
+ res += (scale * scalar_t((tmp >> 2) & 0x3) - zero) * blockvec[k + 1];
+ res += (scale * scalar_t((tmp >> 4) & 0x3) - zero) * blockvec[k + 2];
+ res += (scale * scalar_t((tmp >> 6) & 0x3) - zero) * blockvec[k + 3];
+ res += (scale * scalar_t((tmp >> 8) & 0x3) - zero) * blockvec[k + 4];
+ res += (scale * scalar_t((tmp >> 10) & 0x3) - zero) * blockvec[k + 5];
+ res += (scale * scalar_t((tmp >> 12) & 0x3) - zero) * blockvec[k + 6];
+ res += (scale * scalar_t((tmp >> 14) & 0x3) - zero) * blockvec[k + 7];
+ res += (scale * scalar_t((tmp >> 16) & 0x3) - zero) * blockvec[k + 8];
+ res += (scale * scalar_t((tmp >> 18) & 0x3) - zero) * blockvec[k + 9];
+ res += (scale * scalar_t((tmp >> 20) & 0x3) - zero) * blockvec[k + 10];
+ res += (scale * scalar_t((tmp >> 22) & 0x3) - zero) * blockvec[k + 11];
+ res += (scale * scalar_t((tmp >> 24) & 0x3) - zero) * blockvec[k + 12];
+ res += (scale * scalar_t((tmp >> 26) & 0x3) - zero) * blockvec[k + 13];
+ res += (scale * scalar_t((tmp >> 28) & 0x3) - zero) * blockvec[k + 14];
+ res += (scale * scalar_t((tmp >> 30) & 0x3) - zero) * blockvec[k + 15];
+
+ i += width;
+ k += 16;
+ }
+
+ atomicAdd(&mul[b * width + w], res);
+}
+
+void vecquant3matmul_cuda_old(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ int groupsize
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT3 - 1) / BLOCKHEIGHT3,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH,
+ batch
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant3matmul_cuda_old", ([&] {
+ VecQuant3MatMulKernel_old<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(),
+ batch, vec_height, height, width, zero_width, groupsize
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant3MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+) {
+ int b = blockIdx.z;
+ int h = BLOCKHEIGHT3 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+
+ scalar_t res = 0;
+ int i = width * h + w;
+ int g_h = (h / 3) * 32;
+ int k = 0;
+
+ int z_w = (w / 32) * 3;
+ int z_mod = w % 32;
+ int z_bit;
+
+ if (z_mod != 10){
+ if (z_mod != 21){
+ z_bit = z_mod;
+ if (z_bit > 21){
+ z_bit -= 22;
+ z_bit *= 3;
+ z_bit += 2;
+ z_w += 2;
+ } else if (z_bit > 10){
+ z_bit -= 11;
+ z_bit *= 3;
+ z_bit += 1;
+ z_w += 1;
+ } else {
+ z_bit *= 3;
+ }
+ } else {
+ z_w += 1;
+ }
+ }
+
+ unsigned int tmp1;
+ unsigned int tmp2;
+ unsigned int tmp;
+ unsigned int z_tmp;
+
+ while (k < BLOCKWIDTH) {
+ tmp1 = as_unsigned(mat[i]);
+
+ int g = (g_h + k) / groupsize;
+ scalar_t scale = scales[g * width + w];
+ scalar_t zero;
+ if (z_mod == 10) {
+ z_tmp = (as_unsigned(zeros[g * zero_width + z_w]) >> 30) | ((as_unsigned(zeros[g * zero_width + (z_w + 1)]) << 2) & 0x4);
+ zero = scale * scalar_t(((z_tmp) + 1) & 0x0f);
+ } else if (z_mod == 21){
+ z_tmp = (as_unsigned(zeros[g * zero_width + z_w]) >> 31) | ((as_unsigned(zeros[g * zero_width + (z_w + 1)]) << 1) & 0x6);
+ zero = scale * scalar_t(((z_tmp) + 1) & 0x0f);
+ } else {
+ zero = scale * scalar_t((((as_unsigned(zeros[g * zero_width + z_w]) >> z_bit) & 0x7) + 1) & 0x0f);
+ }
+
+ res += (scale * scalar_t((tmp1 >> 0) & 0x7) - zero) * blockvec[k + 0];
+ res += (scale * scalar_t((tmp1 >> 3) & 0x7) - zero) * blockvec[k + 1];
+ res += (scale * scalar_t((tmp1 >> 6) & 0x7) - zero) * blockvec[k + 2];
+ res += (scale * scalar_t((tmp1 >> 9) & 0x7) - zero) * blockvec[k + 3];
+ res += (scale * scalar_t((tmp1 >> 12) & 0x7) - zero) * blockvec[k + 4];
+ res += (scale * scalar_t((tmp1 >> 15) & 0x7) - zero) * blockvec[k + 5];
+ res += (scale * scalar_t((tmp1 >> 18) & 0x7) - zero) * blockvec[k + 6];
+ res += (scale * scalar_t((tmp1 >> 21) & 0x7) - zero) * blockvec[k + 7];
+ res += (scale * scalar_t((tmp1 >> 24) & 0x7) - zero) * blockvec[k + 8];
+ res += (scale * scalar_t((tmp1 >> 27) & 0x7) - zero) * blockvec[k + 9];
+
+ i += width;
+ tmp2 = as_unsigned(mat[i]);
+ tmp = (tmp1 >> 30) | ((tmp2 << 2) & 0x4);
+ tmp2 >>= 1;
+ res += (scale * scalar_t(tmp) - zero) * blockvec[k + 10];
+ k += 11;
+
+ res += (scale * scalar_t((tmp2 >> 0) & 0x7) - zero) * blockvec[k + 0];
+ res += (scale * scalar_t((tmp2 >> 3) & 0x7) - zero) * blockvec[k + 1];
+ res += (scale * scalar_t((tmp2 >> 6) & 0x7) - zero) * blockvec[k + 2];
+ res += (scale * scalar_t((tmp2 >> 9) & 0x7) - zero) * blockvec[k + 3];
+ res += (scale * scalar_t((tmp2 >> 12) & 0x7) - zero) * blockvec[k + 4];
+ res += (scale * scalar_t((tmp2 >> 15) & 0x7) - zero) * blockvec[k + 5];
+ res += (scale * scalar_t((tmp2 >> 18) & 0x7) - zero) * blockvec[k + 6];
+ res += (scale * scalar_t((tmp2 >> 21) & 0x7) - zero) * blockvec[k + 7];
+ res += (scale * scalar_t((tmp2 >> 24) & 0x7) - zero) * blockvec[k + 8];
+ res += (scale * scalar_t((tmp2 >> 27) & 0x7) - zero) * blockvec[k + 9];
+
+ i += width;
+ tmp1 = as_unsigned(mat[i]);
+ tmp = (tmp2 >> 30) | ((tmp1 << 1) & 0x6);
+ tmp1 >>= 2;
+ res += (scale * scalar_t(tmp) - zero) * blockvec[k + 10];
+ k += 11;
+
+ res += (scale * scalar_t((tmp1 >> 0) & 0x7) - zero) * blockvec[k + 0];
+ res += (scale * scalar_t((tmp1 >> 3) & 0x7) - zero) * blockvec[k + 1];
+ res += (scale * scalar_t((tmp1 >> 6) & 0x7) - zero) * blockvec[k + 2];
+ res += (scale * scalar_t((tmp1 >> 9) & 0x7) - zero) * blockvec[k + 3];
+ res += (scale * scalar_t((tmp1 >> 12) & 0x7) - zero) * blockvec[k + 4];
+ res += (scale * scalar_t((tmp1 >> 15) & 0x7) - zero) * blockvec[k + 5];
+ res += (scale * scalar_t((tmp1 >> 18) & 0x7) - zero) * blockvec[k + 6];
+ res += (scale * scalar_t((tmp1 >> 21) & 0x7) - zero) * blockvec[k + 7];
+ res += (scale * scalar_t((tmp1 >> 24) & 0x7) - zero) * blockvec[k + 8];
+ res += (scale * scalar_t((tmp1 >> 27) & 0x7) - zero) * blockvec[k + 9];
+
+ i += width;
+ k += 10;
+ }
+
+ atomicAdd(&mul[b * width + w], res);
+}
+
+void vecquant4matmul_cuda_old(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ int groupsize
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT4 - 1) / BLOCKHEIGHT4,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH,
+ batch
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant4matmul_cuda_old", ([&] {
+ VecQuant4MatMulKernel_old<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(),
+ batch, vec_height, height, width, zero_width, groupsize
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant4MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+) {
+ int b = blockIdx.z;
+ int h = BLOCKHEIGHT4 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+
+ scalar_t res = 0;
+ int i = width * h + w;
+ int g_h = h * 8;
+ int k = 0;
+
+ int z_w = w / 8;
+ int z_mod = (w % 8) * 4;
+
+ unsigned int tmp;
+
+ while (k < BLOCKWIDTH) {
+ tmp = as_unsigned(mat[i]);
+
+ int g = (g_h + k) / groupsize;
+ scalar_t scale = scales[g * width + w];
+ scalar_t zero = scale * scalar_t((((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod) & 0xF) + 1) & 0x0f);
+
+ res += (scale * scalar_t((tmp >> 0) & 0xF) - zero) * blockvec[k + 0];
+ res += (scale * scalar_t((tmp >> 4) & 0xF) - zero) * blockvec[k + 1];
+ res += (scale * scalar_t((tmp >> 8) & 0xF) - zero) * blockvec[k + 2];
+ res += (scale * scalar_t((tmp >> 12) & 0xF) - zero) * blockvec[k + 3];
+ res += (scale * scalar_t((tmp >> 16) & 0xF) - zero) * blockvec[k + 4];
+ res += (scale * scalar_t((tmp >> 20) & 0xF) - zero) * blockvec[k + 5];
+ res += (scale * scalar_t((tmp >> 24) & 0xF) - zero) * blockvec[k + 6];
+ res += (scale * scalar_t((tmp >> 28) & 0xF) - zero) * blockvec[k + 7];
+
+ i += width;
+ k += 8;
+ }
+
+ atomicAdd(&mul[b * width + w], res);
+}
+
+void vecquant8matmul_cuda_old(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ int groupsize
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT8 - 1) / BLOCKHEIGHT8,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH,
+ batch
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant8matmul_cuda_old", ([&] {
+ VecQuant8MatMulKernel_old<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(),
+ batch, vec_height, height, width, zero_width, groupsize
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant8MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+) {
+ int b = blockIdx.z;
+ int h = BLOCKHEIGHT8 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+
+ scalar_t res = 0;
+ int i = width * h + w;
+ int g_h = h * 4;
+ int k = 0;
+
+ int z_w = w / 4;
+ int z_mod = (w % 4) * 8;
+
+ unsigned int tmp;
+
+ while (k < BLOCKWIDTH) {
+ tmp = as_unsigned(mat[i]);
+
+ int g = (g_h + k) / groupsize;
+ scalar_t scale = scales[g * width + w];
+ scalar_t zero = scale * scalar_t((((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod) & 0xFF) + 1) & 0x0f);
+
+ res += (scale * scalar_t((tmp >> 0) & 0xFF) - zero) * blockvec[k + 0];
+ res += (scale * scalar_t((tmp >> 8) & 0xFF) - zero) * blockvec[k + 1];
+ res += (scale * scalar_t((tmp >> 16) & 0xFF) - zero) * blockvec[k + 2];
+ res += (scale * scalar_t((tmp >> 24) & 0xFF) - zero) * blockvec[k + 3];
+
+ i += width;
+ k += 4;
+ }
+
+ atomicAdd(&mul[b * width + w], res);
+}
+
+
+void vecquant2matmul_faster_cuda_old(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ int groupsize,
+ int vec_height
+) {
+ int batch = vec.size(0);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT2 - 1) / BLOCKHEIGHT2,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH,
+ batch
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ VecQuant2MatMulKernelFaster_old<<>>(
+ (half2*) vec.data_ptr(),
+ mat.data_ptr(),
+ mul.data_ptr(),
+ scales.data_ptr(),
+ zeros.data_ptr(),
+ batch, vec_height, height, width, zero_width, groupsize
+ );
+}
+
+__global__ void VecQuant2MatMulKernelFaster_old(
+ const half2* __restrict__ vec,
+ const int* __restrict__ mat,
+ float* __restrict__ mul,
+ const float* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+) {
+ const int blockwidth2 = BLOCKWIDTH / 2;
+ int b = blockIdx.z;
+ int h = BLOCKHEIGHT2 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ half2 blockvec[blockwidth2];
+ if (threadIdx.x < blockwidth2)
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * blockwidth2 + threadIdx.x];
+
+ __shared__ half2 deq2[16][16];
+ int val = threadIdx.x / 16;
+ int off = threadIdx.x % 16;
+ for (; val < 16; val += BLOCKWIDTH / 16) {
+ deq2[val][off] = __halves2half2(
+ __int2half_rn(val & 0x3), __int2half_rn(val >> 2)
+ );
+ }
+
+ int i = width * h + w;
+ int g_h = h * 16;
+ int k = 0;
+
+ int z_w = w / 16;
+ int z_mod = (w % 16) * 2;
+
+ float res = 0;
+ half2 res2;
+
+ unsigned int tmp;
+
+ __syncthreads();
+
+ while (k < blockwidth2) {
+ int g = (g_h + (k * 2)) / groupsize;
+ float scale_f = scales[g * width + w];
+ half2 scale = __float2half2_rn(scale_f);
+ half2 zero = __float2half2_rn(-(scale_f * ((((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod) & 0x3) + 1) & 0x0f)));
+
+ std::memset(&res2, 0, sizeof(half2));
+ tmp = as_unsigned(mat[i]);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 0) & 0xf][off], scale, zero), blockvec[k + 0], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 4) & 0xf][off], scale, zero), blockvec[k + 1], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 8) & 0xf][off], scale, zero), blockvec[k + 2], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 12) & 0xf][off], scale, zero), blockvec[k + 3], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 16) & 0xf][off], scale, zero), blockvec[k + 4], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 20) & 0xf][off], scale, zero), blockvec[k + 5], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 24) & 0xf][off], scale, zero), blockvec[k + 6], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 28) & 0xf][off], scale, zero), blockvec[k + 7], res2);
+ i += width;
+ k += 8;
+ res += __low2float(res2) + __high2float(res2);
+ }
+
+ atomicAdd(&mul[b * width + w], res);
+}
+
+void vecquant3matmul_faster_cuda_old(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ int groupsize,
+ int vec_height
+) {
+ int batch = vec.size(0);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT3 - 1) / BLOCKHEIGHT3,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH,
+ batch
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ VecQuant3MatMulKernelFaster_old<<>>(
+ (half2*) vec.data_ptr(),
+ mat.data_ptr(),
+ mul.data_ptr(),
+ scales.data_ptr(),
+ zeros.data_ptr(),
+ batch, vec_height, height, width, zero_width, groupsize
+ );
+}
+
+__global__ void VecQuant3MatMulKernelFaster_old(
+ const half2* __restrict__ vec,
+ const int* __restrict__ mat,
+ float* __restrict__ mul,
+ const float* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+) {
+ const int blockwidth2 = BLOCKWIDTH / 2;
+ int b = blockIdx.z;
+ int h = BLOCKHEIGHT3 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ half2 blockvec[blockwidth2];
+ if (threadIdx.x < blockwidth2)
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * blockwidth2 + threadIdx.x];
+
+ __shared__ half2 deq2[64][32];
+ int val = threadIdx.x / 32;
+ int off = threadIdx.x % 32;
+ for (; val < 64; val += BLOCKWIDTH / 32) {
+ deq2[val][off] = __halves2half2(
+ __int2half_rn(val & 0x7), __int2half_rn(val >> 3)
+ );
+ }
+
+ int i = width * h + w;
+ int g_h = (h / 3) * 32;
+ int k = 0;
+
+ int z_w = (w / 32) * 3;
+ int z_mod = w % 32;
+ int z_bit;
+
+ if (z_mod != 10){
+ if (z_mod != 21){
+ z_bit = z_mod;
+ if (z_bit > 21){
+ z_bit -= 22;
+ z_bit *= 3;
+ z_bit += 2;
+ z_w += 2;
+ } else if (z_bit > 10){
+ z_bit -= 11;
+ z_bit *= 3;
+ z_bit += 1;
+ z_w += 1;
+ } else {
+ z_bit *= 3;
+ }
+ } else {
+ z_w += 1;
+ }
+ }
+
+ float res = 0;
+ half2 res2;
+
+ unsigned int tmp1;
+ unsigned int tmp2;
+ unsigned int tmp;
+ unsigned int z_tmp;
+
+ __syncthreads();
+
+ while (k < blockwidth2) {
+ int g = (g_h + (k * 2)) / groupsize;
+ float scale_f = scales[g * width + w];
+ half2 scale = __float2half2_rn(scale_f);
+ half2 zero;
+ if (z_mod == 10) {
+ z_tmp = (as_unsigned(zeros[g * zero_width + z_w]) >> 30) | ((as_unsigned(zeros[g * zero_width + (z_w + 1)]) << 2) & 0x4);
+ zero = __float2half2_rn(-(scale_f * (((z_tmp) + 1) & 0x0f)));
+ } else if (z_mod == 21){
+ z_tmp = (as_unsigned(zeros[g * zero_width + z_w]) >> 31) | ((as_unsigned(zeros[g * zero_width + (z_w + 1)]) << 1) & 0x6);
+ zero = __float2half2_rn(-(scale_f * (((z_tmp) + 1) & 0x0f)));
+ } else {
+ zero = __float2half2_rn(-(scale_f * ((((as_unsigned(zeros[g * zero_width + z_w]) >> z_bit) & 0x7) + 1) & 0x0f)));
+ }
+
+ std::memset(&res2, 0, sizeof(half2));
+ tmp1 = as_unsigned(mat[i]);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 0) & 0x3f][off], scale, zero), blockvec[k + 0], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 6) & 0x3f][off], scale, zero), blockvec[k + 1], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 12) & 0x3f][off], scale, zero), blockvec[k + 2], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 18) & 0x3f][off], scale, zero), blockvec[k + 3], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 24) & 0x3f][off], scale, zero), blockvec[k + 4], res2);
+ i += width;
+ tmp2 = as_unsigned(mat[i]);
+ tmp = (tmp1 >> 30) | ((tmp2 << 2) & 0x3c);
+ res2 = __hfma2(__hfma2(deq2[tmp][off], scale, zero), blockvec[k + 5], res2);
+ tmp2 >>= 4;
+ k += 6;
+ res2 = __hfma2(__hfma2(deq2[(tmp2 >> 0) & 0x3f][off], scale, zero), blockvec[k + 0], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp2 >> 6) & 0x3f][off], scale, zero), blockvec[k + 1], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp2 >> 12) & 0x3f][off], scale, zero), blockvec[k + 2], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp2 >> 18) & 0x3f][off], scale, zero), blockvec[k + 3], res2);
+ i += width;
+ tmp1 = as_unsigned(mat[i]);
+ tmp = (tmp2 >> 24) | ((tmp1 << 4) & 0x30);
+ res2 = __hfma2(__hfma2(deq2[tmp][off], scale, zero), blockvec[k + 4], res2);
+ tmp1 >>= 2;
+ k += 5;
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 0) & 0x3f][off], scale, zero), blockvec[k + 0], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 6) & 0x3f][off], scale, zero), blockvec[k + 1], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 12) & 0x3f][off], scale, zero), blockvec[k + 2], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 18) & 0x3f][off], scale, zero), blockvec[k + 3], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 24) & 0x3f][off], scale, zero), blockvec[k + 4], res2);
+ i += width;
+ k += 5;
+ res += __low2float(res2) + __high2float(res2);
+ }
+
+ atomicAdd(&mul[b * width + w], res);
+}
+
+void vecquant4matmul_faster_cuda_old(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ int groupsize,
+ int vec_height
+) {
+ int batch = vec.size(0);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT4 - 1) / BLOCKHEIGHT4,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH,
+ batch
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ VecQuant4MatMulKernelFaster_old<<>>(
+ (half2*) vec.data_ptr(),
+ mat.data_ptr(),
+ mul.data_ptr(),
+ scales.data_ptr(),
+ zeros.data_ptr(),
+ batch, vec_height, height, width, zero_width, groupsize
+ );
+}
+
+__global__ void VecQuant4MatMulKernelFaster_old(
+ const half2* __restrict__ vec,
+ const int* __restrict__ mat,
+ float* __restrict__ mul,
+ const float* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+) {
+ const int blockwidth2 = BLOCKWIDTH / 2;
+ int b = blockIdx.z;
+ int h = BLOCKHEIGHT4 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ half2 blockvec[blockwidth2];
+ if (threadIdx.x < blockwidth2)
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * blockwidth2 + threadIdx.x];
+
+ __shared__ half2 deq2[256][8];
+ int val = threadIdx.x / 8;
+ int off = threadIdx.x % 8;
+ for (; val < 256; val += BLOCKWIDTH / 8) {
+ deq2[val][off] = __halves2half2(
+ __int2half_rn(val & 0xF), __int2half_rn(val >> 4)
+ );
+ }
+
+ int i = width * h + w;
+ int g_h = h * 8;
+ int k = 0;
+
+ int z_w = w / 8;
+ int z_mod = (w % 8) * 4;
+
+ float res = 0;
+ half2 res2;
+
+ unsigned int tmp;
+
+ __syncthreads();
+
+ while (k < blockwidth2) {
+ int g = (g_h + (k * 2)) / groupsize;
+ float scale_f = scales[g * width + w];
+
+ half2 scale = __float2half2_rn(scale_f);
+ half2 zero = __float2half2_rn(-(scale_f * ((((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod) & 0xF) + 1) & 0x0f)));
+
+ //std::memset(&res2, 0, sizeof(half2));
+
+ //res2 = __float2half2_rn((float)0.);
+
+ std::memset(&res2, 0, sizeof(half2));
+ tmp = as_unsigned(mat[i]);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 0) & 0xff][off], scale, zero), blockvec[k + 0], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 8) & 0xff][off], scale, zero), blockvec[k + 1], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 16) & 0xff][off], scale, zero), blockvec[k + 2], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 24) & 0xff][off], scale, zero), blockvec[k + 3], res2);
+ i += width;
+ k += 4;
+
+ res += __low2float(res2) + __high2float(res2);
+
+ }
+
+ atomicAdd(&mul[b * width + w], res);
+}
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/cuda_64/autogptq_cuda_64.cpp b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/cuda_64/autogptq_cuda_64.cpp
new file mode 100644
index 0000000000000000000000000000000000000000..dad762e6e5a0da0a8e9704b97c6ddfe113f8e183
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/cuda_64/autogptq_cuda_64.cpp
@@ -0,0 +1,187 @@
+#include
+#include
+#include
+
+void vecquant2matmul_cuda(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+);
+
+void vecquant2matmul(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant2matmul_cuda(vec, mat, mul, scales, zeros, g_idx);
+}
+
+void vecquant3matmul_cuda(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+);
+
+void vecquant3matmul(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant3matmul_cuda(vec, mat, mul, scales, zeros, g_idx);
+}
+
+void vecquant4matmul_cuda(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+);
+
+void vecquant4matmul(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant4matmul_cuda(vec, mat, mul, scales, zeros, g_idx);
+}
+
+void vecquant8matmul_cuda(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+);
+
+void vecquant8matmul(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant8matmul_cuda(vec, mat, mul, scales, zeros, g_idx);
+}
+
+
+// old
+
+void vecquant2matmul_cuda_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+);
+
+void vecquant2matmul_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant2matmul_cuda_old(vec, mat, mul, scales, zeros,groupsize);
+}
+
+void vecquant3matmul_cuda_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+);
+
+void vecquant3matmul_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant3matmul_cuda_old(vec, mat, mul, scales, zeros, groupsize);
+}
+
+void vecquant4matmul_cuda_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+);
+
+void vecquant4matmul_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant4matmul_cuda_old(vec, mat, mul, scales, zeros, groupsize);
+}
+
+void vecquant8matmul_cuda_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+);
+
+void vecquant8matmul_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant8matmul_cuda_old(vec, mat, mul, scales, zeros, groupsize);
+}
+
+void vecquant2matmul_faster_cuda_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize, int vec_height
+);
+
+void vecquant2matmul_faster_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize, int vec_height
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant2matmul_faster_cuda_old(vec, mat, mul, scales, zeros, groupsize, vec_height);
+}
+
+void vecquant3matmul_faster_cuda_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize, int vec_height
+);
+
+void vecquant3matmul_faster_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize, int vec_height
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant3matmul_faster_cuda_old(vec, mat, mul, scales, zeros, groupsize, vec_height);
+}
+
+void vecquant4matmul_faster_cuda_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize, int vec_height
+);
+
+void vecquant4matmul_faster_old(
+ torch::Tensor vec, torch::Tensor mat, torch::Tensor mul,
+ torch::Tensor scales, torch::Tensor zeros,
+ int groupsize, int vec_height
+) {
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(vec));
+ vecquant4matmul_faster_cuda_old(vec, mat, mul, scales, zeros, groupsize, vec_height);
+}
+
+
+PYBIND11_MODULE(TORCH_EXTENSION_NAME, m) {
+ m.def("vecquant2matmul", &vecquant2matmul, "Vector 2-bit Quantized Matrix Multiplication (CUDA) (desc_act)");
+ m.def("vecquant3matmul", &vecquant3matmul, "Vector 3-bit Quantized Matrix Multiplication (CUDA) (desc_act)");
+ m.def("vecquant4matmul", &vecquant4matmul, "Vector 4-bit Quantized Matrix Multiplication (CUDA) (desc_act)");
+ m.def("vecquant8matmul", &vecquant8matmul, "Vector 8-bit Quantized Matrix Multiplication (CUDA) (desc_act)");
+
+ m.def("vecquant2matmul_old", &vecquant2matmul_old, "Vector 2-bit Quantized Matrix Multiplication (CUDA)");
+ m.def("vecquant3matmul_old", &vecquant3matmul_old, "Vector 3-bit Quantized Matrix Multiplication (CUDA)");
+ m.def("vecquant4matmul_old", &vecquant4matmul_old, "Vector 4-bit Quantized Matrix Multiplication (CUDA)");
+ m.def("vecquant8matmul_old", &vecquant8matmul_old, "Vector 8-bit Quantized Matrix Multiplication (CUDA)");
+ m.def("vecquant2matmul_faster_old", &vecquant2matmul_faster_old, "Vector 2-bit Quantized Matrix Multiplication (CUDA), faster version");
+ m.def("vecquant3matmul_faster_old", &vecquant3matmul_faster_old, "Vector 3-bit Quantized Matrix Multiplication (CUDA), faster version");
+ m.def("vecquant4matmul_faster_old", &vecquant4matmul_faster_old, "Vector 4-bit Quantized Matrix Multiplication (CUDA), faster version");
+}
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/cuda_64/autogptq_cuda_kernel_64.cu b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/cuda_64/autogptq_cuda_kernel_64.cu
new file mode 100644
index 0000000000000000000000000000000000000000..10c63617ed0cb24c32dfec2b5077b33edc01b92b
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/cuda_64/autogptq_cuda_kernel_64.cu
@@ -0,0 +1,1431 @@
+#include
+#include
+#include
+#include
+#include
+
+// atomicAdd for double-precision floating-point numbers on hardware with
+// compute capability < 6.0 from:
+// https://docs.nvidia.com/cuda/cuda-c-programming-guide/index.html#atomic-functions
+// #if defined(__CUDA_ARCH__) && __CUDA_ARCH__ < 600
+// __device__ double atomicAdd(
+// double* address,
+// double val
+// ) {
+// unsigned long long int* address_as_ull = (unsigned long long int*)address;
+// unsigned long long int old = *address_as_ull, assumed;
+//
+// do {
+// assumed = old;
+// old = atomicCAS(
+// address_as_ull,
+// assumed,
+// __double_as_longlong(val + __longlong_as_double(assumed))
+// );
+//
+// // Note: uses integer comparison to avoid hang in case of NaN (since NaN != NaN)
+// } while (assumed != old);
+//
+// return __longlong_as_double(old);
+// }
+// #endif
+
+
+#if (defined(__CUDA_ARCH__) && __CUDA_ARCH__ < 700) || defined(USE_ROCM)
+// adapted from https://github.com/torch/cutorch/blob/master/lib/THC/THCAtomics.cuh
+__device__ __forceinline__ void atomicAdd(c10::Half* address, c10::Half val) {
+ unsigned int *address_as_ui = reinterpret_cast(reinterpret_cast(address) - (reinterpret_cast(address) & 2));
+ unsigned int old = *address_as_ui;
+ unsigned int assumed;
+
+ do {
+ assumed = old;
+ unsigned short hsum = reinterpret_cast(address) & 2 ? (old >> 16) : (old & 0xffff);
+ hsum += val;
+ old = reinterpret_cast(address) & 2
+ ? (old & 0xffff) | (hsum << 16)
+ : (old & 0xffff0000) | hsum;
+ old = atomicCAS(address_as_ui, assumed, old);
+
+ // Note: uses integer comparison to avoid hang in case of NaN (since NaN != NaN)
+ } while (assumed != old);
+}
+__device__ __forceinline__ void atomicAdd(__half* address, c10::Half val) {
+ unsigned int * address_as_ui = (unsigned int *) ((char *)address - ((size_t)address & 2));
+ unsigned int old = *address_as_ui;
+ unsigned int assumed;
+
+ do {
+ assumed = old;
+ __half_raw hsum;
+ hsum.x = (size_t)address & 2 ? (old >> 16) : (old & 0xffff);
+ half tmpres = __hadd(hsum, val);
+ hsum = __half_raw(tmpres);
+ old = (size_t)address & 2 ? (old & 0xffff) | (hsum.x << 16) : (old & 0xffff0000) | hsum.x;
+ old = atomicCAS(address_as_ui, assumed, old);
+ } while (assumed != old);
+}
+#endif
+
+
+template
+__global__ void VecQuant2MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+);
+
+template
+__global__ void VecQuant3MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+);
+
+template
+__global__ void VecQuant4MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+);
+
+
+template
+__global__ void VecQuant8MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+);
+
+template
+__global__ void VecQuant2MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+);
+
+template
+__global__ void VecQuant3MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+);
+
+template
+__global__ void VecQuant4MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+);
+
+template
+__global__ void VecQuant8MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+);
+
+__global__ void VecQuant2MatMulKernelFaster_old(
+ const half2* __restrict__ vec,
+ const int* __restrict__ mat,
+ float* __restrict__ mul,
+ const float* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+);
+
+__global__ void VecQuant3MatMulKernelFaster_old(
+ const half2* __restrict__ vec,
+ const int* __restrict__ mat,
+ float* __restrict__ mul,
+ const float* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+);
+
+__global__ void VecQuant4MatMulKernelFaster_old(
+ const half2* __restrict__ vec,
+ const int* __restrict__ mat,
+ float* __restrict__ mul,
+ const float* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+);
+
+
+const int BLOCKWIDTH = 64;
+const int BLOCKHEIGHT2 = 4;
+const int BLOCKHEIGHT3 = 6;
+const int BLOCKHEIGHT4 = 8;
+const int BLOCKHEIGHT8 = 16;
+
+__device__ inline unsigned int as_unsigned(int i) {
+ return *reinterpret_cast(&i);
+}
+
+__device__ inline int as_int(int i) {
+ return *reinterpret_cast(&i);
+}
+
+
+void vecquant2matmul_cuda(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT2 - 1) / BLOCKHEIGHT2,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant2matmul_cuda", ([&] {
+ VecQuant2MatMulKernel<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(), g_idx.data(),
+ batch, vec_height, height, width, zero_width
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant2MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+) {
+ int h = BLOCKHEIGHT2 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ int i = width * h + w;
+ int g_h = h * 16;
+ int k;
+ unsigned int g;
+ scalar_t w_tmp;
+
+ int z_w = w / 16;
+ int z_mod = (w % 16) * 2;
+
+ float weight[BLOCKWIDTH];
+
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ int k_w = (k / 16);
+ int k_bit = (k % 16) * 2;
+
+ g = as_int(g_idx[g_h + k]);
+ scalar_t scale = scales[g * width + w];
+
+ // Avoid overflows with & 0x0f.
+ scalar_t zero = scalar_t(((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod & 0x3) + 1) & 0x0f);
+
+ w_tmp = ((as_unsigned(mat[i + (k_w * width)]) >> k_bit) & 0x3);
+
+ weight[k] = scale * (w_tmp - zero);
+ }
+
+ scalar_t res;
+ for (int b = 0; b < batch; ++b){
+ res = 0;
+
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ res += weight[k] * blockvec[k];
+ }
+ atomicAdd(&mul[b * width + w], res);
+ __syncthreads();
+ }
+}
+
+void vecquant3matmul_cuda(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT3 - 1) / BLOCKHEIGHT3,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant3matmul_cuda", ([&] {
+ VecQuant3MatMulKernel<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(), g_idx.data(),
+ batch, vec_height, height, width, zero_width
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant3MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+) {
+ int h = BLOCKHEIGHT3 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ int i = width * h + w;
+ int g_h = (h / 3) * 32;
+ int k;
+ unsigned int g;
+ scalar_t w_tmp;
+
+ int z_w = (w / 32) * 3;
+ int z_mod = w % 32;
+ int z_bit;
+ unsigned int z_tmp;
+ if (z_mod != 10){
+ if (z_mod != 21){
+ z_bit = z_mod;
+ if (z_bit > 21){
+ z_bit -= 22;
+ z_bit *= 3;
+ z_bit += 2;
+ z_w += 2;
+ } else if (z_bit > 10){
+ z_bit -= 11;
+ z_bit *= 3;
+ z_bit += 1;
+ z_w += 1;
+ } else {
+ z_bit *= 3;
+ }
+ } else {
+ z_w += 1;
+ }
+ }
+
+ float weight[BLOCKWIDTH];
+
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ int k_w = (k / 32) * 3;
+ int k_mod = k % 32;
+ int k_bit;
+
+ if (k_mod != 10){
+ if (k_mod != 21){
+ k_bit = k_mod;
+ if (k_bit > 21){
+ k_bit -= 22;
+ k_bit *= 3;
+ k_bit += 2;
+ k_w += 2;
+ } else if (k_bit > 10){
+ k_bit -= 11;
+ k_bit *= 3;
+ k_bit += 1;
+ k_w += 1;
+ } else {
+ k_bit *= 3;
+ }
+ } else {
+ k_w += 1;
+ }
+ }
+
+ g = as_int(g_idx[g_h + k]);
+ scalar_t scale = scales[g * width + w];
+ scalar_t zero;
+ if (z_mod == 10) {
+ z_tmp = (as_unsigned(zeros[g * zero_width + z_w]) >> 30) | ((as_unsigned(zeros[g * zero_width + (z_w + 1)]) << 2) & 0x4);
+ zero = scalar_t(((z_tmp) + 1) & 0x0f); // Avoid overflows
+ } else if (z_mod == 21){
+ z_tmp = (as_unsigned(zeros[g * zero_width + z_w]) >> 31) | ((as_unsigned(zeros[g * zero_width + (z_w + 1)]) << 1) & 0x6);
+ zero = scalar_t(((z_tmp) + 1) & 0x0f); // Avoid overflows
+ } else {
+ zero = scalar_t((((as_unsigned(zeros[g * zero_width + z_w]) >> z_bit) & 0x7) + 1) & 0x0f);
+ }
+
+ if (k_mod == 10) {
+ w_tmp = (as_unsigned(mat[i + (k_w * width)]) >> 30) | ((as_unsigned(mat[i + ((k_w + 1)* width)]) << 2) & 0x4);
+ } else if (k_mod == 21){
+ w_tmp = (as_unsigned(mat[i + (k_w * width)]) >> 31) | ((as_unsigned(mat[i + ((k_w + 1)* width)]) << 1) & 0x6);
+ } else {
+ w_tmp = ((as_unsigned(mat[i + (k_w * width)]) >> k_bit) & 0x7);
+ }
+ weight[k] = scale * (w_tmp - zero);
+ }
+
+ scalar_t res;
+ for (int b = 0; b < batch; ++b){
+ res = 0;
+
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ res += weight[k] * blockvec[k];
+ }
+ atomicAdd(&mul[b * width + w], res);
+ __syncthreads();
+ }
+}
+
+void vecquant4matmul_cuda(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT4 - 1) / BLOCKHEIGHT4,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant4matmul_cuda", ([&] {
+ VecQuant4MatMulKernel<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(), g_idx.data(),
+ batch, vec_height, height, width, zero_width
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant4MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+) {
+ int h = BLOCKHEIGHT4 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ int i = width * h + w;
+ int g_h = h * 8;
+ int k;
+ unsigned int g;
+ scalar_t w_tmp;
+
+
+ int z_w = w / 8;
+ int z_mod = (w % 8) * 4;
+
+ float weight[BLOCKWIDTH];
+
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ int k_w = (k / 8);
+ int k_bit = (k % 8) * 4;
+
+ g = as_int(g_idx[g_h + k]);
+ scalar_t scale = scales[g * width + w];
+ scalar_t zero = scalar_t((((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod) & 0xF) + 1) & 0x0f);
+
+ w_tmp = ((as_unsigned(mat[i + (k_w * width)]) >> k_bit) & 0xF);
+
+ weight[k] = scale * (w_tmp - zero);
+ }
+
+ scalar_t res;
+ for (int b = 0; b < batch; ++b){
+ res = 0;
+
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ res += weight[k] * blockvec[k];
+ }
+ atomicAdd(&mul[b * width + w], res);
+ __syncthreads();
+ }
+}
+
+void vecquant8matmul_cuda(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ torch::Tensor g_idx
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT8 - 1) / BLOCKHEIGHT8,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant8matmul_cuda", ([&] {
+ VecQuant8MatMulKernel<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(), g_idx.data(),
+ batch, vec_height, height, width, zero_width
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant8MatMulKernel(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ const int* __restrict__ g_idx,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width
+) {
+ int h = BLOCKHEIGHT8 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ int i = width * h + w;
+ int g_h = h * 4;
+ int k;
+ unsigned int g;
+ scalar_t w_tmp;
+
+ int z_w = w / 4;
+ int z_mod = (w % 4) * 8;
+
+ float weight[BLOCKWIDTH];
+
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ int k_w = (k / 4);
+ int k_bit = (k % 4) * 8;
+
+ g = as_int(g_idx[g_h + k]);
+ scalar_t scale = scales[g * width + w];
+ scalar_t zero = scalar_t((((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod) & 0xFF) + 1) & 0x0f);
+
+ w_tmp = ((as_unsigned(mat[i + (k_w * width)]) >> k_bit) & 0xFF);
+
+ weight[k] = scale * (w_tmp - zero);
+ }
+
+ scalar_t res;
+ for (int b = 0; b < batch; ++b){
+ res = 0;
+
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+ for (k = 0; k < BLOCKWIDTH; ++k){
+ res += weight[k] * blockvec[k];
+ }
+ atomicAdd(&mul[b * width + w], res);
+ __syncthreads();
+ }
+}
+
+
+void vecquant2matmul_cuda_old(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ int groupsize
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT2 - 1) / BLOCKHEIGHT2,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH,
+ batch
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant2matmul_cuda_old", ([&] {
+ VecQuant2MatMulKernel_old<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(),
+ batch, vec_height, height, width, zero_width, groupsize
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant2MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+) {
+ int b = blockIdx.z;
+ int h = BLOCKHEIGHT2 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+
+ scalar_t res = 0;
+ int i = width * h + w;
+ int g_h = h * 16;
+ int k = 0;
+
+ int z_w = w / 16;
+ int z_mod = (w % 16) * 2;
+
+ unsigned int tmp;
+
+ while (k < BLOCKWIDTH) {
+ tmp = as_unsigned(mat[i]);
+
+ int g = (g_h + k) / groupsize;
+ scalar_t scale = scales[g * width + w];
+ scalar_t zero = scale * scalar_t(((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod & 0x3) + 1) & 0x0f);
+
+ res += (scale * scalar_t((tmp >> 0) & 0x3) - zero) * blockvec[k + 0];
+ res += (scale * scalar_t((tmp >> 2) & 0x3) - zero) * blockvec[k + 1];
+ res += (scale * scalar_t((tmp >> 4) & 0x3) - zero) * blockvec[k + 2];
+ res += (scale * scalar_t((tmp >> 6) & 0x3) - zero) * blockvec[k + 3];
+ res += (scale * scalar_t((tmp >> 8) & 0x3) - zero) * blockvec[k + 4];
+ res += (scale * scalar_t((tmp >> 10) & 0x3) - zero) * blockvec[k + 5];
+ res += (scale * scalar_t((tmp >> 12) & 0x3) - zero) * blockvec[k + 6];
+ res += (scale * scalar_t((tmp >> 14) & 0x3) - zero) * blockvec[k + 7];
+ res += (scale * scalar_t((tmp >> 16) & 0x3) - zero) * blockvec[k + 8];
+ res += (scale * scalar_t((tmp >> 18) & 0x3) - zero) * blockvec[k + 9];
+ res += (scale * scalar_t((tmp >> 20) & 0x3) - zero) * blockvec[k + 10];
+ res += (scale * scalar_t((tmp >> 22) & 0x3) - zero) * blockvec[k + 11];
+ res += (scale * scalar_t((tmp >> 24) & 0x3) - zero) * blockvec[k + 12];
+ res += (scale * scalar_t((tmp >> 26) & 0x3) - zero) * blockvec[k + 13];
+ res += (scale * scalar_t((tmp >> 28) & 0x3) - zero) * blockvec[k + 14];
+ res += (scale * scalar_t((tmp >> 30) & 0x3) - zero) * blockvec[k + 15];
+
+ i += width;
+ k += 16;
+ }
+
+ atomicAdd(&mul[b * width + w], res);
+}
+
+void vecquant3matmul_cuda_old(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ int groupsize
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT3 - 1) / BLOCKHEIGHT3,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH,
+ batch
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant3matmul_cuda_old", ([&] {
+ VecQuant3MatMulKernel_old<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(),
+ batch, vec_height, height, width, zero_width, groupsize
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant3MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+) {
+ int b = blockIdx.z;
+ int h = BLOCKHEIGHT3 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+
+ scalar_t res = 0;
+ int i = width * h + w;
+ int g_h = (h / 3) * 32;
+ int k = 0;
+
+ int z_w = (w / 32) * 3;
+ int z_mod = w % 32;
+ int z_bit;
+
+ if (z_mod != 10){
+ if (z_mod != 21){
+ z_bit = z_mod;
+ if (z_bit > 21){
+ z_bit -= 22;
+ z_bit *= 3;
+ z_bit += 2;
+ z_w += 2;
+ } else if (z_bit > 10){
+ z_bit -= 11;
+ z_bit *= 3;
+ z_bit += 1;
+ z_w += 1;
+ } else {
+ z_bit *= 3;
+ }
+ } else {
+ z_w += 1;
+ }
+ }
+
+ unsigned int tmp1;
+ unsigned int tmp2;
+ unsigned int tmp;
+ unsigned int z_tmp;
+
+ while (k < BLOCKWIDTH) {
+ tmp1 = as_unsigned(mat[i]);
+
+ int g = (g_h + k) / groupsize;
+ scalar_t scale = scales[g * width + w];
+ scalar_t zero;
+ if (z_mod == 10) {
+ z_tmp = (as_unsigned(zeros[g * zero_width + z_w]) >> 30) | ((as_unsigned(zeros[g * zero_width + (z_w + 1)]) << 2) & 0x4);
+ zero = scale * scalar_t(((z_tmp) + 1) & 0x0f);
+ } else if (z_mod == 21){
+ z_tmp = (as_unsigned(zeros[g * zero_width + z_w]) >> 31) | ((as_unsigned(zeros[g * zero_width + (z_w + 1)]) << 1) & 0x6);
+ zero = scale * scalar_t(((z_tmp) + 1) & 0x0f);
+ } else {
+ zero = scale * scalar_t((((as_unsigned(zeros[g * zero_width + z_w]) >> z_bit) & 0x7) + 1) & 0x0f);
+ }
+
+ res += (scale * scalar_t((tmp1 >> 0) & 0x7) - zero) * blockvec[k + 0];
+ res += (scale * scalar_t((tmp1 >> 3) & 0x7) - zero) * blockvec[k + 1];
+ res += (scale * scalar_t((tmp1 >> 6) & 0x7) - zero) * blockvec[k + 2];
+ res += (scale * scalar_t((tmp1 >> 9) & 0x7) - zero) * blockvec[k + 3];
+ res += (scale * scalar_t((tmp1 >> 12) & 0x7) - zero) * blockvec[k + 4];
+ res += (scale * scalar_t((tmp1 >> 15) & 0x7) - zero) * blockvec[k + 5];
+ res += (scale * scalar_t((tmp1 >> 18) & 0x7) - zero) * blockvec[k + 6];
+ res += (scale * scalar_t((tmp1 >> 21) & 0x7) - zero) * blockvec[k + 7];
+ res += (scale * scalar_t((tmp1 >> 24) & 0x7) - zero) * blockvec[k + 8];
+ res += (scale * scalar_t((tmp1 >> 27) & 0x7) - zero) * blockvec[k + 9];
+
+ i += width;
+ tmp2 = as_unsigned(mat[i]);
+ tmp = (tmp1 >> 30) | ((tmp2 << 2) & 0x4);
+ tmp2 >>= 1;
+ res += (scale * scalar_t(tmp) - zero) * blockvec[k + 10];
+ k += 11;
+
+ res += (scale * scalar_t((tmp2 >> 0) & 0x7) - zero) * blockvec[k + 0];
+ res += (scale * scalar_t((tmp2 >> 3) & 0x7) - zero) * blockvec[k + 1];
+ res += (scale * scalar_t((tmp2 >> 6) & 0x7) - zero) * blockvec[k + 2];
+ res += (scale * scalar_t((tmp2 >> 9) & 0x7) - zero) * blockvec[k + 3];
+ res += (scale * scalar_t((tmp2 >> 12) & 0x7) - zero) * blockvec[k + 4];
+ res += (scale * scalar_t((tmp2 >> 15) & 0x7) - zero) * blockvec[k + 5];
+ res += (scale * scalar_t((tmp2 >> 18) & 0x7) - zero) * blockvec[k + 6];
+ res += (scale * scalar_t((tmp2 >> 21) & 0x7) - zero) * blockvec[k + 7];
+ res += (scale * scalar_t((tmp2 >> 24) & 0x7) - zero) * blockvec[k + 8];
+ res += (scale * scalar_t((tmp2 >> 27) & 0x7) - zero) * blockvec[k + 9];
+
+ i += width;
+ tmp1 = as_unsigned(mat[i]);
+ tmp = (tmp2 >> 30) | ((tmp1 << 1) & 0x6);
+ tmp1 >>= 2;
+ res += (scale * scalar_t(tmp) - zero) * blockvec[k + 10];
+ k += 11;
+
+ res += (scale * scalar_t((tmp1 >> 0) & 0x7) - zero) * blockvec[k + 0];
+ res += (scale * scalar_t((tmp1 >> 3) & 0x7) - zero) * blockvec[k + 1];
+ res += (scale * scalar_t((tmp1 >> 6) & 0x7) - zero) * blockvec[k + 2];
+ res += (scale * scalar_t((tmp1 >> 9) & 0x7) - zero) * blockvec[k + 3];
+ res += (scale * scalar_t((tmp1 >> 12) & 0x7) - zero) * blockvec[k + 4];
+ res += (scale * scalar_t((tmp1 >> 15) & 0x7) - zero) * blockvec[k + 5];
+ res += (scale * scalar_t((tmp1 >> 18) & 0x7) - zero) * blockvec[k + 6];
+ res += (scale * scalar_t((tmp1 >> 21) & 0x7) - zero) * blockvec[k + 7];
+ res += (scale * scalar_t((tmp1 >> 24) & 0x7) - zero) * blockvec[k + 8];
+ res += (scale * scalar_t((tmp1 >> 27) & 0x7) - zero) * blockvec[k + 9];
+
+ i += width;
+ k += 10;
+ }
+
+ atomicAdd(&mul[b * width + w], res);
+}
+
+void vecquant4matmul_cuda_old(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ int groupsize
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT4 - 1) / BLOCKHEIGHT4,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH,
+ batch
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant4matmul_cuda_old", ([&] {
+ VecQuant4MatMulKernel_old<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(),
+ batch, vec_height, height, width, zero_width, groupsize
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant4MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+) {
+ int b = blockIdx.z;
+ int h = BLOCKHEIGHT4 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+
+ scalar_t res = 0;
+ int i = width * h + w;
+ int g_h = h * 8;
+ int k = 0;
+
+ int z_w = w / 8;
+ int z_mod = (w % 8) * 4;
+
+ unsigned int tmp;
+
+ while (k < BLOCKWIDTH) {
+ tmp = as_unsigned(mat[i]);
+
+ int g = (g_h + k) / groupsize;
+ scalar_t scale = scales[g * width + w];
+ scalar_t zero = scale * scalar_t((((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod) & 0xF) + 1) & 0x0f);
+
+ res += (scale * scalar_t((tmp >> 0) & 0xF) - zero) * blockvec[k + 0];
+ res += (scale * scalar_t((tmp >> 4) & 0xF) - zero) * blockvec[k + 1];
+ res += (scale * scalar_t((tmp >> 8) & 0xF) - zero) * blockvec[k + 2];
+ res += (scale * scalar_t((tmp >> 12) & 0xF) - zero) * blockvec[k + 3];
+ res += (scale * scalar_t((tmp >> 16) & 0xF) - zero) * blockvec[k + 4];
+ res += (scale * scalar_t((tmp >> 20) & 0xF) - zero) * blockvec[k + 5];
+ res += (scale * scalar_t((tmp >> 24) & 0xF) - zero) * blockvec[k + 6];
+ res += (scale * scalar_t((tmp >> 28) & 0xF) - zero) * blockvec[k + 7];
+
+ i += width;
+ k += 8;
+ }
+
+ atomicAdd(&mul[b * width + w], res);
+}
+
+void vecquant8matmul_cuda_old(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ int groupsize
+) {
+ int batch = vec.size(0);
+ int vec_height = vec.size(1);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT8 - 1) / BLOCKHEIGHT8,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH,
+ batch
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ AT_DISPATCH_FLOATING_TYPES(
+ vec.type(), "vecquant8matmul_cuda_old", ([&] {
+ VecQuant8MatMulKernel_old<<>>(
+ vec.data(), mat.data(), mul.data(),
+ scales.data(), zeros.data(),
+ batch, vec_height, height, width, zero_width, groupsize
+ );
+ })
+ );
+}
+
+template
+__global__ void VecQuant8MatMulKernel_old(
+ const scalar_t* __restrict__ vec,
+ const int* __restrict__ mat,
+ scalar_t* __restrict__ mul,
+ const scalar_t* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+) {
+ int b = blockIdx.z;
+ int h = BLOCKHEIGHT8 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ scalar_t blockvec[BLOCKWIDTH];
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * BLOCKWIDTH + threadIdx.x];
+ __syncthreads();
+
+ scalar_t res = 0;
+ int i = width * h + w;
+ int g_h = h * 4;
+ int k = 0;
+
+ int z_w = w / 4;
+ int z_mod = (w % 4) * 8;
+
+ unsigned int tmp;
+
+ while (k < BLOCKWIDTH) {
+ tmp = as_unsigned(mat[i]);
+
+ int g = (g_h + k) / groupsize;
+ scalar_t scale = scales[g * width + w];
+ scalar_t zero = scale * scalar_t((((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod) & 0xFF) + 1) & 0x0f);
+
+ res += (scale * scalar_t((tmp >> 0) & 0xFF) - zero) * blockvec[k + 0];
+ res += (scale * scalar_t((tmp >> 8) & 0xFF) - zero) * blockvec[k + 1];
+ res += (scale * scalar_t((tmp >> 16) & 0xFF) - zero) * blockvec[k + 2];
+ res += (scale * scalar_t((tmp >> 24) & 0xFF) - zero) * blockvec[k + 3];
+
+ i += width;
+ k += 4;
+ }
+
+ atomicAdd(&mul[b * width + w], res);
+}
+
+
+void vecquant2matmul_faster_cuda_old(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ int groupsize,
+ int vec_height
+) {
+ int batch = vec.size(0);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT2 - 1) / BLOCKHEIGHT2,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH,
+ batch
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ VecQuant2MatMulKernelFaster_old<<>>(
+ (half2*) vec.data_ptr(),
+ mat.data_ptr(),
+ mul.data_ptr(),
+ scales.data_ptr(),
+ zeros.data_ptr(),
+ batch, vec_height, height, width, zero_width, groupsize
+ );
+}
+
+__global__ void VecQuant2MatMulKernelFaster_old(
+ const half2* __restrict__ vec,
+ const int* __restrict__ mat,
+ float* __restrict__ mul,
+ const float* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+) {
+ const int blockwidth2 = BLOCKWIDTH / 2;
+ int b = blockIdx.z;
+ int h = BLOCKHEIGHT2 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ half2 blockvec[blockwidth2];
+ if (threadIdx.x < blockwidth2)
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * blockwidth2 + threadIdx.x];
+
+ __shared__ half2 deq2[16][16];
+ int val = threadIdx.x / 16;
+ int off = threadIdx.x % 16;
+ for (; val < 16; val += BLOCKWIDTH / 16) {
+ deq2[val][off] = __halves2half2(
+ __int2half_rn(val & 0x3), __int2half_rn(val >> 2)
+ );
+ }
+
+ int i = width * h + w;
+ int g_h = h * 16;
+ int k = 0;
+
+ int z_w = w / 16;
+ int z_mod = (w % 16) * 2;
+
+ float res = 0;
+ half2 res2;
+
+ unsigned int tmp;
+
+ __syncthreads();
+
+ while (k < blockwidth2) {
+ int g = (g_h + (k * 2)) / groupsize;
+ float scale_f = scales[g * width + w];
+ half2 scale = __float2half2_rn(scale_f);
+ half2 zero = __float2half2_rn(-(scale_f * ((((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod) & 0x3) + 1) & 0x0f)));
+
+ std::memset(&res2, 0, sizeof(half2));
+ tmp = as_unsigned(mat[i]);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 0) & 0xf][off], scale, zero), blockvec[k + 0], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 4) & 0xf][off], scale, zero), blockvec[k + 1], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 8) & 0xf][off], scale, zero), blockvec[k + 2], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 12) & 0xf][off], scale, zero), blockvec[k + 3], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 16) & 0xf][off], scale, zero), blockvec[k + 4], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 20) & 0xf][off], scale, zero), blockvec[k + 5], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 24) & 0xf][off], scale, zero), blockvec[k + 6], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 28) & 0xf][off], scale, zero), blockvec[k + 7], res2);
+ i += width;
+ k += 8;
+ res += __low2float(res2) + __high2float(res2);
+ }
+
+ atomicAdd(&mul[b * width + w], res);
+}
+
+void vecquant3matmul_faster_cuda_old(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ int groupsize,
+ int vec_height
+) {
+ int batch = vec.size(0);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT3 - 1) / BLOCKHEIGHT3,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH,
+ batch
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ VecQuant3MatMulKernelFaster_old<<>>(
+ (half2*) vec.data_ptr(),
+ mat.data_ptr(),
+ mul.data_ptr(),
+ scales.data_ptr(),
+ zeros.data_ptr(),
+ batch, vec_height, height, width, zero_width, groupsize
+ );
+}
+
+__global__ void VecQuant3MatMulKernelFaster_old(
+ const half2* __restrict__ vec,
+ const int* __restrict__ mat,
+ float* __restrict__ mul,
+ const float* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+) {
+ const int blockwidth2 = BLOCKWIDTH / 2;
+ int b = blockIdx.z;
+ int h = BLOCKHEIGHT3 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ half2 blockvec[blockwidth2];
+ if (threadIdx.x < blockwidth2)
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * blockwidth2 + threadIdx.x];
+
+ __shared__ half2 deq2[64][32];
+ int val = threadIdx.x / 32;
+ int off = threadIdx.x % 32;
+ for (; val < 64; val += BLOCKWIDTH / 32) {
+ deq2[val][off] = __halves2half2(
+ __int2half_rn(val & 0x7), __int2half_rn(val >> 3)
+ );
+ }
+
+ int i = width * h + w;
+ int g_h = (h / 3) * 32;
+ int k = 0;
+
+ int z_w = (w / 32) * 3;
+ int z_mod = w % 32;
+ int z_bit;
+
+ if (z_mod != 10){
+ if (z_mod != 21){
+ z_bit = z_mod;
+ if (z_bit > 21){
+ z_bit -= 22;
+ z_bit *= 3;
+ z_bit += 2;
+ z_w += 2;
+ } else if (z_bit > 10){
+ z_bit -= 11;
+ z_bit *= 3;
+ z_bit += 1;
+ z_w += 1;
+ } else {
+ z_bit *= 3;
+ }
+ } else {
+ z_w += 1;
+ }
+ }
+
+ float res = 0;
+ half2 res2;
+
+ unsigned int tmp1;
+ unsigned int tmp2;
+ unsigned int tmp;
+ unsigned int z_tmp;
+
+ __syncthreads();
+
+ while (k < blockwidth2) {
+ int g = (g_h + (k * 2)) / groupsize;
+ float scale_f = scales[g * width + w];
+ half2 scale = __float2half2_rn(scale_f);
+ half2 zero;
+ if (z_mod == 10) {
+ z_tmp = (as_unsigned(zeros[g * zero_width + z_w]) >> 30) | ((as_unsigned(zeros[g * zero_width + (z_w + 1)]) << 2) & 0x4);
+ zero = __float2half2_rn(-(scale_f * (((z_tmp) + 1) & 0x0f)));
+ } else if (z_mod == 21){
+ z_tmp = (as_unsigned(zeros[g * zero_width + z_w]) >> 31) | ((as_unsigned(zeros[g * zero_width + (z_w + 1)]) << 1) & 0x6);
+ zero = __float2half2_rn(-(scale_f * (((z_tmp) + 1) & 0x0f)));
+ } else {
+ zero = __float2half2_rn(-(scale_f * ((((as_unsigned(zeros[g * zero_width + z_w]) >> z_bit) & 0x7) + 1) & 0x0f)));
+ }
+
+ std::memset(&res2, 0, sizeof(half2));
+ tmp1 = as_unsigned(mat[i]);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 0) & 0x3f][off], scale, zero), blockvec[k + 0], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 6) & 0x3f][off], scale, zero), blockvec[k + 1], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 12) & 0x3f][off], scale, zero), blockvec[k + 2], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 18) & 0x3f][off], scale, zero), blockvec[k + 3], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 24) & 0x3f][off], scale, zero), blockvec[k + 4], res2);
+ i += width;
+ tmp2 = as_unsigned(mat[i]);
+ tmp = (tmp1 >> 30) | ((tmp2 << 2) & 0x3c);
+ res2 = __hfma2(__hfma2(deq2[tmp][off], scale, zero), blockvec[k + 5], res2);
+ tmp2 >>= 4;
+ k += 6;
+ res2 = __hfma2(__hfma2(deq2[(tmp2 >> 0) & 0x3f][off], scale, zero), blockvec[k + 0], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp2 >> 6) & 0x3f][off], scale, zero), blockvec[k + 1], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp2 >> 12) & 0x3f][off], scale, zero), blockvec[k + 2], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp2 >> 18) & 0x3f][off], scale, zero), blockvec[k + 3], res2);
+ i += width;
+ tmp1 = as_unsigned(mat[i]);
+ tmp = (tmp2 >> 24) | ((tmp1 << 4) & 0x30);
+ res2 = __hfma2(__hfma2(deq2[tmp][off], scale, zero), blockvec[k + 4], res2);
+ tmp1 >>= 2;
+ k += 5;
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 0) & 0x3f][off], scale, zero), blockvec[k + 0], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 6) & 0x3f][off], scale, zero), blockvec[k + 1], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 12) & 0x3f][off], scale, zero), blockvec[k + 2], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 18) & 0x3f][off], scale, zero), blockvec[k + 3], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp1 >> 24) & 0x3f][off], scale, zero), blockvec[k + 4], res2);
+ i += width;
+ k += 5;
+ res += __low2float(res2) + __high2float(res2);
+ }
+
+ atomicAdd(&mul[b * width + w], res);
+}
+
+void vecquant4matmul_faster_cuda_old(
+ torch::Tensor vec,
+ torch::Tensor mat,
+ torch::Tensor mul,
+ torch::Tensor scales,
+ torch::Tensor zeros,
+ int groupsize,
+ int vec_height
+) {
+ int batch = vec.size(0);
+ int height = mat.size(0);
+ int width = mat.size(1);
+ int zero_width = zeros.size(1);
+
+ dim3 blocks(
+ (height + BLOCKHEIGHT4 - 1) / BLOCKHEIGHT4,
+ (width + BLOCKWIDTH - 1) / BLOCKWIDTH,
+ batch
+ );
+ dim3 threads(BLOCKWIDTH);
+
+ VecQuant4MatMulKernelFaster_old<<>>(
+ (half2*) vec.data_ptr(),
+ mat.data_ptr(),
+ mul.data_ptr(),
+ scales.data_ptr(),
+ zeros.data_ptr(),
+ batch, vec_height, height, width, zero_width, groupsize
+ );
+}
+
+__global__ void VecQuant4MatMulKernelFaster_old(
+ const half2* __restrict__ vec,
+ const int* __restrict__ mat,
+ float* __restrict__ mul,
+ const float* __restrict__ scales,
+ const int* __restrict__ zeros,
+ int batch,
+ int vec_height,
+ int height,
+ int width,
+ int zero_width,
+ int groupsize
+) {
+ const int blockwidth2 = BLOCKWIDTH / 2;
+ int b = blockIdx.z;
+ int h = BLOCKHEIGHT4 * blockIdx.x;
+ int w = BLOCKWIDTH * blockIdx.y + threadIdx.x;
+
+ __shared__ half2 blockvec[blockwidth2];
+ if (threadIdx.x < blockwidth2)
+ blockvec[threadIdx.x] = vec[b * vec_height + blockIdx.x * blockwidth2 + threadIdx.x];
+
+ __shared__ half2 deq2[256][8];
+ int val = threadIdx.x / 8;
+ int off = threadIdx.x % 8;
+ for (; val < 256; val += BLOCKWIDTH / 8) {
+ deq2[val][off] = __halves2half2(
+ __int2half_rn(val & 0xF), __int2half_rn(val >> 4)
+ );
+ }
+
+ int i = width * h + w;
+ int g_h = h * 8;
+ int k = 0;
+
+ int z_w = w / 8;
+ int z_mod = (w % 8) * 4;
+
+ float res = 0;
+ half2 res2;
+
+ unsigned int tmp;
+
+ __syncthreads();
+
+ while (k < blockwidth2) {
+ int g = (g_h + (k * 2)) / groupsize;
+ float scale_f = scales[g * width + w];
+ half2 scale = __float2half2_rn(scale_f);
+ half2 zero = __float2half2_rn(-(scale_f * ((((as_unsigned(zeros[g * zero_width + z_w]) >> z_mod) & 0xF) + 1) & 0x0f)));
+
+ std::memset(&res2, 0, sizeof(half2));
+ tmp = as_unsigned(mat[i]);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 0) & 0xff][off], scale, zero), blockvec[k + 0], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 8) & 0xff][off], scale, zero), blockvec[k + 1], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 16) & 0xff][off], scale, zero), blockvec[k + 2], res2);
+ res2 = __hfma2(__hfma2(deq2[(tmp >> 24) & 0xff][off], scale, zero), blockvec[k + 3], res2);
+ i += width;
+ k += 4;
+ res += __low2float(res2) + __high2float(res2);
+ }
+
+ atomicAdd(&mul[b * width + w], res);
+}
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cu_compat.cuh b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cu_compat.cuh
new file mode 100644
index 0000000000000000000000000000000000000000..c5258813e147554e033eaf9a80c27dd694a50961
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cu_compat.cuh
@@ -0,0 +1,58 @@
+// Adapted from turboderp exllama: https://github.com/turboderp/exllama
+
+#ifndef _cuda_compat_cuh
+#define _cuda_compat_cuh
+
+// atomicAdd for half types, to support CC < 7.x
+
+__device__ __forceinline__ void atomicAdd_half(half* address, half val)
+{
+ unsigned int * address_as_ui = (unsigned int *) ((char *)address - ((size_t)address & 2));
+ unsigned int old = *address_as_ui;
+ unsigned int assumed;
+
+ do
+ {
+ assumed = old;
+ __half_raw hsum;
+ hsum.x = (size_t)address & 2 ? (old >> 16) : (old & 0xffff);
+ half tmpres = __hadd(hsum, val);
+ hsum = __half_raw(tmpres);
+ old = (size_t)address & 2 ? (old & 0xffff) | (hsum.x << 16) : (old & 0xffff0000) | hsum.x;
+ old = atomicCAS(address_as_ui, assumed, old);
+ }
+ while (assumed != old);
+}
+
+// atomicAdd for half2 types
+
+__device__ __forceinline__ void atomicAdd_half2(half2* address, half2 val)
+{
+ unsigned int* address_as_ui = (unsigned int*)address;
+ unsigned int old = *address_as_ui;
+ unsigned int assumed;
+ do
+ {
+ assumed = old;
+ half2 old_val = *((half2*)&old);
+ half2 new_val = __hadd2(old_val, val);
+ old = atomicCAS(address_as_ui, assumed, *((unsigned int*)&new_val));
+ }
+ while (assumed != old);
+}
+
+//
+
+#if defined(__CUDA_ARCH__) || defined(USE_ROCM)
+#if __CUDA_ARCH__ < 700 || defined(USE_ROCM)
+
+__device__ __forceinline__ void atomicAdd(half* address, half val) { atomicAdd_half(address, val); }
+
+#if __CUDA_ARCH__ < 600 || defined(USE_ROCM)
+__device__ __forceinline__ void atomicAdd(half2* address, half2 val) { atomicAdd_half2(address, val); }
+#endif
+
+#endif
+#endif
+
+#endif
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_buffers.cu b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_buffers.cu
new file mode 100644
index 0000000000000000000000000000000000000000..4416027c8387a17726f061519f49cd181843ac1d
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_buffers.cu
@@ -0,0 +1,75 @@
+// Adapted from turboderp exllama: https://github.com/turboderp/exllama
+
+#define _cuda_buffers_cu
+#include "cuda_buffers.cuh"
+
+CudaBuffers* g_buffers[CUDA_MAX_DEVICES] = {NULL};
+// __constant__ half2 q4_table[16][256];
+// half2 q4_table_host[16][256];
+// bool q4_table_init = false;
+
+CudaBuffers::CudaBuffers
+(
+ int _device,
+ int _temp_state_size,
+ half* _temp_state,
+ half* _temp_dq
+) :
+ device(_device),
+ temp_state_size(_temp_state_size),
+ temp_state(_temp_state),
+ temp_dq(_temp_dq)
+{
+ cudaSetDevice(_device);
+
+ cudaStreamCreate(&alt_stream_1);
+ cudaStreamCreate(&alt_stream_2);
+ cudaStreamCreate(&alt_stream_3);
+ cudaEventCreate(&alt_stream_1_done);
+ cudaEventCreate(&alt_stream_2_done);
+ cudaEventCreate(&alt_stream_3_done);
+}
+
+CudaBuffers::~CudaBuffers()
+{
+ cudaStreamDestroy(alt_stream_1);
+ cudaStreamDestroy(alt_stream_2);
+ cudaStreamDestroy(alt_stream_3);
+ cudaEventDestroy(alt_stream_1_done);
+ cudaEventDestroy(alt_stream_2_done);
+ cudaEventDestroy(alt_stream_3_done);
+}
+
+CudaBuffers* get_buffers(const int device_index)
+{
+ return g_buffers[device_index];
+}
+
+void prepare_buffers_cuda
+(
+ int _device,
+ int _temp_state_size,
+ half* _temp_state,
+ half* _temp_dq
+)
+{
+ CudaBuffers* buffers = new CudaBuffers
+ (
+ _device,
+ _temp_state_size,
+ _temp_state,
+ _temp_dq
+ );
+
+ g_buffers[_device] = buffers;
+}
+
+void cleanup_buffers_cuda()
+{
+ for (int i = 0; i < CUDA_MAX_DEVICES; i++)
+ {
+ if (!g_buffers[i]) continue;
+ delete g_buffers[i];
+ g_buffers[i] = NULL;
+ }
+}
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_buffers.cuh b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_buffers.cuh
new file mode 100644
index 0000000000000000000000000000000000000000..0bf2057c665cbfad46461d437ef5fe44b02f8f2e
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_buffers.cuh
@@ -0,0 +1,55 @@
+// Adapted from turboderp exllama: https://github.com/turboderp/exllama
+
+#ifndef _cuda_buffers_cuh
+#define _cuda_buffers_cuh
+
+#include
+#include
+#include
+#include
+
+const int CUDA_MAX_DEVICES = 16;
+
+// #ifndef _cuda_buffers_cu
+// extern __constant__ half2 q4_table[16][256];
+// #endif
+
+class CudaBuffers
+{
+public:
+ int device;
+
+ half* temp_state; // [max_hidden_rows * intermediate_size]
+ int temp_state_size;
+ half* temp_dq; // size of largest quant tensor * 8
+
+ cudaStream_t alt_stream_1;
+ cudaStream_t alt_stream_2;
+ cudaStream_t alt_stream_3;
+ cudaEvent_t alt_stream_1_done;
+ cudaEvent_t alt_stream_2_done;
+ cudaEvent_t alt_stream_3_done;
+
+ CudaBuffers
+ (
+ int _device,
+ int _temp_state_size,
+ half* _temp_state,
+ half* _temp_dq
+ );
+ ~CudaBuffers();
+};
+
+CudaBuffers* get_buffers(const int device_index);
+
+void prepare_buffers_cuda
+(
+ int _device,
+ int _temp_state_size,
+ half* _temp_state,
+ half* _temp_dq
+);
+
+void cleanup_buffers_cuda();
+
+#endif
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/column_remap.cu b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/column_remap.cu
new file mode 100644
index 0000000000000000000000000000000000000000..30e4039dd2e94691b3e303a99dfb7bf6aa873b4e
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/column_remap.cu
@@ -0,0 +1,63 @@
+// Adapted from turboderp exllama: https://github.com/turboderp/exllama
+
+#include "column_remap.cuh"
+#include "../util.cuh"
+
+const int SHUF_BLOCKSIZE_X = 256;
+const int SHUF_BLOCKSIZE_Y = 16;
+
+__global__ void column_remap_kernel
+(
+ const half* __restrict__ x,
+ half* __restrict__ x_new,
+ const int x_width,
+ const int x_height,
+ const uint32_t* x_map
+)
+{
+ int x_column = SHUF_BLOCKSIZE_X * blockIdx.x + threadIdx.x;
+ int x_row = SHUF_BLOCKSIZE_Y * blockIdx.y;
+ if (x_column >= x_width) return;
+ //if (x_row >= x_height) return;
+
+ int x_stride = x_width;
+ int x_idx = x_row * x_stride + x_column;
+
+ int x_row_end = min(x_row + SHUF_BLOCKSIZE_Y, x_height);
+ int x_idx_end = x_row_end * x_stride + x_column;
+
+ int s_column = x_map[x_column];
+ int s_idx = x_row * x_stride + s_column;
+
+ while (x_idx < x_idx_end)
+ {
+ x_new[x_idx] = x[s_idx];
+ x_idx += x_stride;
+ s_idx += x_stride;
+ }
+}
+
+// Remap columns in x to correspond to sequential group index before matmul
+//
+// perform x -> seq_x such that seq_x @ seq_w == x @ w
+
+void column_remap_cuda
+(
+ const half* x,
+ half* x_new,
+ const int x_height,
+ const int x_width,
+ const uint32_t* x_map
+)
+{
+ dim3 threads(SHUF_BLOCKSIZE_X, 1, 1);
+
+ dim3 blocks
+ (
+ (x_width + SHUF_BLOCKSIZE_X - 1) / SHUF_BLOCKSIZE_X,
+ (x_height + SHUF_BLOCKSIZE_Y - 1) / SHUF_BLOCKSIZE_Y,
+ 1
+ );
+
+ column_remap_kernel<<>>(x, x_new, x_width, x_height, x_map);
+}
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/column_remap.cuh b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/column_remap.cuh
new file mode 100644
index 0000000000000000000000000000000000000000..6571c17d6fd51b85276b00fed5a48ea36df40a60
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/column_remap.cuh
@@ -0,0 +1,19 @@
+// Adapted from turboderp exllama: https://github.com/turboderp/exllama
+
+#ifndef _column_remap_cuh
+#define _column_remap_cuh
+
+#include
+#include
+#include
+
+void column_remap_cuda
+(
+ const half* x,
+ half* x_new,
+ const int x_height,
+ const int x_width,
+ const uint32_t* x_map
+);
+
+#endif
\ No newline at end of file
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/q4_matmul.cu b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/q4_matmul.cu
new file mode 100644
index 0000000000000000000000000000000000000000..a407c6b445adf9ef52fde346a92618456150ed7c
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/q4_matmul.cu
@@ -0,0 +1,260 @@
+// Adapted from turboderp exllama: https://github.com/turboderp/exllama
+
+#include "q4_matmul.cuh"
+#include "column_remap.cuh"
+#include "../util.cuh"
+#include "../matrix.cuh"
+#include "../cu_compat.cuh"
+#include "../cuda_buffers.cuh"
+#if defined(USE_ROCM)
+#include "../hip_compat.cuh"
+#endif
+
+const int THREADS_X = 32; // Block size and thread count along columns in w and out
+const int THREADS_Y = 1; // Block size and thread count along rows in x and out
+
+typedef void (*fp_q4_matmul_kernel)
+(
+ const half*,
+ const uint32_t*,
+ half*,
+ const half*,
+ const uint32_t*,
+ const int,
+ const int,
+ const int,
+ const int,
+ const int,
+ const uint32_t*,
+ bool
+);
+
+template
+__global__ void q4_matmul_kernel
+(
+ const half* __restrict__ x,
+ const uint32_t* __restrict__ w,
+ half* __restrict__ out,
+ const half* __restrict__ w_scales,
+ const uint32_t* __restrict__ w_zeros,
+ const int height,
+ const int dim,
+ const int width,
+ const int groupsize,
+ const int block_size_z,
+ const uint32_t* __restrict__ x_map,
+ bool no_zero
+)
+{
+ // Start of block
+
+ int x_column = block_size_z * blockIdx.z;
+ int x_column_end = min(dim, block_size_z * (blockIdx.z + 1));
+
+ int w_column = THREADS_X * blockIdx.x + threadIdx.x;
+ int x_row = THREADS_Y * blockIdx.y + threadIdx.y;
+
+ int iterations = (x_column_end - x_column) / 8;
+
+ // Views
+
+ MatrixView_half x_(x, height, dim);
+ MatrixView_half w_scales_(w_scales, dim / groupsize, width);
+ MatrixView_q4_row w_zeros_(w_zeros, dim / groupsize, width);
+ MatrixView_q4_column w_(w, dim, width);
+ MatrixView_half_rw out_(out, height, width);
+
+ // Zero output
+
+ if (!no_zero && blockIdx.z == 0 && (threadIdx.x & 1) == 0)
+ {
+ *((uint32_t*) out_.item_ptr(x_row, w_column)) = 0;
+ __syncthreads();
+ }
+
+ // Loop over part of x row (and w column)
+
+ half2 acc = {};
+ half acc_h = {};
+
+ if constexpr (use_groupsize)
+ {
+ // For quant matrices where groupsize divides BLOCK_SIZE_Z we always start on a group boundary, so this
+ // could be slightly faster
+
+ for (int k = x_column, group = x_column / groupsize; k < x_column + iterations * 8; group++, k += groupsize)
+ {
+ if constexpr (use_half2)
+ {
+ half2 w_scale = w_scales_.item_half2half2(group, w_column);
+ uint32_t w_zero = (w_zeros_.item(group, w_column) + 1) & 0x0f; // Avoid overflows.
+
+ if constexpr (use_x_map) acc = dot_product_8_x_map(acc, x_, x_row, k, w_, k, w_column, w_scale, w_zero, groupsize / 8, x_map);
+ else acc = dot_product_8 (acc, x_, x_row, k, w_, k, w_column, w_scale, w_zero, groupsize / 8);
+ }
+ else
+ {
+ half w_scale = w_scales_.item(group, w_column);
+ uint32_t w_zero = (w_zeros_.item(group, w_column) + 1) & 0x0f; // Avoid overflows.
+
+ if constexpr (use_x_map) acc_h = dot_product_8_x_map_h(acc_h, x_, x_row, k, w_, k, w_column, w_scale, w_zero, groupsize / 8, x_map);
+ else acc_h = dot_product_8_h (acc_h, x_, x_row, k, w_, k, w_column, w_scale, w_zero, groupsize / 8);
+ }
+ }
+ }
+ else
+ {
+ // Otherwise assume groupsize is a multiple of 8, do 8 columns per iteration and trust the cache
+
+ for (int k = x_column; k < x_column + iterations * 8; k += 8)
+ {
+ if constexpr (use_half2)
+ {
+ int group = k / groupsize;
+ half2 w_scale = w_scales_.item_half2half2(group, w_column);
+ uint32_t w_zero = (w_zeros_.item(group, w_column) + 1) & 0x0f; // Avoid overflows.
+
+ if constexpr (use_x_map) acc = dot_product_8_x_map(acc, x_, x_row, k, w_, k, w_column, w_scale, w_zero, 1, x_map);
+ else acc = dot_product_8 (acc, x_, x_row, k, w_, k, w_column, w_scale, w_zero, 1);
+ }
+ else
+ {
+ int group = k / groupsize;
+ half w_scale = w_scales_.item(group, w_column);
+ uint32_t w_zero = (w_zeros_.item(group, w_column) + 1) & 0x0f; // Avoid overflows.
+
+ if constexpr (use_x_map) acc_h = dot_product_8_x_map_h(acc_h, x_, x_row, k, w_, k, w_column, w_scale, w_zero, 1, x_map);
+ else acc_h = dot_product_8_h (acc_h, x_, x_row, k, w_, k, w_column, w_scale, w_zero, 1);
+ }
+ }
+ }
+
+ // Add to block result
+
+ if constexpr (use_half2)
+ {
+ half result = __hadd(__low2half(acc), __high2half(acc));
+ atomicAdd(out_.item_ptr(x_row, w_column), result);
+ }
+ else
+ {
+ atomicAdd(out_.item_ptr(x_row, w_column), acc_h);
+ }
+}
+
+fp_q4_matmul_kernel q4_matmul_kernel_pick(ExLlamaTuning* tuningParams, int block_size_z, int groupsize, uint32_t* x_map)
+{
+ //
+ if (tuningParams->matmul_no_half2) {
+ if (block_size_z % groupsize == 0) {
+ if (x_map) return q4_matmul_kernel;
+ else return q4_matmul_kernel;
+ } else {
+ if (x_map) return q4_matmul_kernel;
+ else return q4_matmul_kernel;
+ }
+ } else {
+ if (block_size_z % groupsize == 0)
+ {
+ if (x_map) return q4_matmul_kernel;
+ else return q4_matmul_kernel;
+ } else {
+ if (x_map) return q4_matmul_kernel;
+ else return q4_matmul_kernel;
+ }
+ }
+};
+
+// Compute y = x @ w
+
+void q4_matmul_cuda
+(
+ ExLlamaTuning* tuningParams,
+ const half* x,
+ const int x_height,
+ const Q4Matrix* w,
+ half* out,
+ bool no_zero,
+ cudaStream_t alt_stream
+)
+{
+ int height = x_height;
+ int dim = w->height;
+ int width = w->width;
+
+ cudaSetDevice(w->device);
+
+ uint32_t* x_map = w->cuda_x_map;
+ const half* x_mapped = x;
+ if (x_map && !tuningParams->matmul_fused_remap && !alt_stream)
+ {
+ CudaBuffers* buffers = get_buffers(w->device);
+ column_remap_cuda(x, buffers->temp_state, x_height, dim, w->cuda_x_map);
+ x_mapped = buffers->temp_state;
+ x_map = NULL;
+ }
+
+ int block_size_z;
+ if (w->width == 4096) block_size_z = 384; // 7B
+ else if (w->width == 11008) block_size_z = 256;
+ else if (w->width == 5120) block_size_z = 384; // 13B
+ else if (w->width == 13824) block_size_z = 256;
+ else if (w->width == 6656) block_size_z = 256; // 33B
+ else if (w->width == 17920) block_size_z = 128;
+ else block_size_z = 256;
+
+ //if (!no_zero) cudaMemsetAsync(out, 0, x_height * w->width * sizeof(half));
+
+ dim3 threads(THREADS_X, THREADS_Y, 1);
+
+ dim3 blocks
+ (
+ (width + threads.x - 1) / threads.x,
+ (height + threads.y - 1) / threads.y,
+ (dim + block_size_z - 1) / block_size_z
+ );
+
+ fp_q4_matmul_kernel kernel = q4_matmul_kernel_pick(tuningParams, block_size_z, w->groupsize, x_map);
+
+ kernel<<>> (x_mapped, w->cuda_qweight, out, w->cuda_scales, w->cuda_qzeros, height, dim, width, w->groupsize, block_size_z, x_map, no_zero);
+}
+
+void q4_matmul_recons_cuda
+(
+ ExLlamaTuning* tuningParams,
+ const half* x,
+ const int x_height,
+ Q4Matrix* w,
+ half* out,
+ const cublasHandle_t handle,
+ bool no_zero
+)
+{
+ int height = x_height;
+ int dim = w->height;
+ int width = w->width;
+
+ cudaSetDevice(w->device);
+ CudaBuffers* buffers = get_buffers(w->device);
+
+ const half* x_mapped = x;
+ if (w->cuda_x_map)
+ {
+ TORCH_CHECK(buffers->temp_state_size >= x_height * dim, "The temp_state buffer is too small in the exllama backend for GPTQ with act-order. Please call the exllama_set_max_input_length function to increase the buffer size for a sequence length >=", x_height, ":\nfrom auto_gptq import exllama_set_max_input_length\nmodel = exllama_set_max_input_length(model, max_input_length=", x_height, ")");
+ column_remap_cuda(x, buffers->temp_state, x_height, dim, w->cuda_x_map);
+ x_mapped = buffers->temp_state;
+ }
+
+ w->reconstruct(buffers->temp_dq);
+
+#if defined(__CUDA_ARCH__) && __CUDA_ARCH__ < 700
+ const float alpha = 1.0f;
+ const float beta = no_zero ? 1.0f : 0.0f;
+ cublasSgemmEx(handle, CUBLAS_OP_N, CUBLAS_OP_N, width, height, dim, &alpha, buffers->temp_dq, CUDA_R_16F, width,
+ x_mapped, CUDA_R_16F, dim, &beta, out, CUDA_R_16F, width);
+#else
+ const half alpha = __float2half(1.0f);
+ const half beta = no_zero ? __float2half(1.0f) : __float2half(0.0f);
+ cublasHgemm(handle, CUBLAS_OP_N, CUBLAS_OP_N, width, height, dim, &alpha, buffers->temp_dq, width, x_mapped, dim, &beta, out, width);
+#endif
+}
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/q4_matmul.cuh b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/q4_matmul.cuh
new file mode 100644
index 0000000000000000000000000000000000000000..49967648f2fddfd2254fd377302977d49b7dd0b4
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/q4_matmul.cuh
@@ -0,0 +1,43 @@
+// Adapted from turboderp exllama: https://github.com/turboderp/exllama
+
+#ifndef _q4_matmul_cuh
+#define _q4_matmul_cuh
+
+#include
+#include
+#include
+#include
+#include
+
+#include "q4_matrix.cuh"
+#include "../tuning.h"
+
+// Workaround for hipify_python using rocblas instead of hipblas.
+#if defined(USE_ROCM)
+#include
+#define rocblas_handle hipblasHandle_t
+#endif
+
+void q4_matmul_cuda
+(
+ ExLlamaTuning* tuningParams,
+ const half* x,
+ const int x_height,
+ const Q4Matrix* w,
+ half* out,
+ bool no_zero = false,
+ cudaStream_t alt_stream = NULL
+);
+
+void q4_matmul_recons_cuda
+(
+ ExLlamaTuning* tuningParams,
+ const half* x,
+ const int x_height,
+ Q4Matrix* w,
+ half* out,
+ const cublasHandle_t handle,
+ bool no_zero = false
+);
+
+#endif
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/q4_matrix.cu b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/q4_matrix.cu
new file mode 100644
index 0000000000000000000000000000000000000000..1906232030c9830bf9c8a0fd04f21e9289d1a997
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/q4_matrix.cu
@@ -0,0 +1,225 @@
+// Adapted from turboderp exllama: https://github.com/turboderp/exllama
+
+#include "q4_matrix.cuh"
+#include
+#include "../util.cuh"
+#include "../matrix.cuh"
+
+using namespace std;
+
+const int UNSHUF_BLOCKSIZE_X = 64;
+
+const int RECONS_THREADS_X = 64; // Block size and thread count along columns in out, each thread converts 1 column
+const int RECONS_THREADS_Y = 1; // Block size and thread count along rows in x and out, each thread converts 8 rows
+
+vector g_q4_matrices;
+
+void g_q4_keep_matrix(Q4Matrix* m)
+{
+ g_q4_matrices.push_back(m);
+}
+
+void g_q4_free_matrices()
+{
+ for (const auto& m : g_q4_matrices) delete m;
+ g_q4_matrices.clear();
+}
+
+Q4Matrix::Q4Matrix
+(
+ const int _height,
+ const int _width,
+ const int _groups,
+
+ uint32_t* _qweight,
+ uint32_t* _qzeros,
+ half* _scales,
+ uint32_t* _g_idx,
+
+ const int _device
+) :
+ height(_height),
+ width(_width),
+ groups(_groups),
+ device(_device)
+{
+ cudaSetDevice(device);
+
+ cuda_qweight = _qweight;
+ cuda_qzeros = _qzeros;
+ cuda_scales = _scales;
+
+ groupsize = height / groups;
+
+ if (_g_idx) make_sequential(_g_idx);
+}
+
+Q4Matrix::~Q4Matrix()
+{
+}
+
+// Make sequential
+
+__global__ void make_sequential_kernel
+(
+ const uint32_t* __restrict__ w,
+ uint32_t* __restrict__ w_new,
+ const uint32_t* __restrict__ x_map,
+ const int w_height,
+ const int w_width
+)
+{
+ const uint64_t* w2 = (uint64_t*) w;
+ uint64_t* w_new2 = (uint64_t*) w_new;
+ int w2_stride = w_width >> 1;
+
+ int w2_column = UNSHUF_BLOCKSIZE_X * blockIdx.x + threadIdx.x;
+ if (w2_column >= w2_stride) return;
+
+ int w_new2_row = blockIdx.y;
+
+ int x_map_idx = w_new2_row << 3;
+
+ uint64_t dst = 0;
+
+ #pragma unroll
+ for (int i = 0; i < 8; i++)
+ {
+ int source_row = x_map[x_map_idx++];
+
+ int w2_row = source_row >> 3;
+ int w2_subrow = source_row & 0x07;
+ int w2_row_shift = w2_subrow << 2;
+ int wnew2_row_shift = i << 2;
+
+ uint64_t src = w2[w2_row * w2_stride + w2_column];
+ src >>= w2_row_shift;
+ src &= 0x0000000f0000000f;
+ src <<= wnew2_row_shift;
+ dst |= src;
+ }
+
+ w_new2[w_new2_row * w2_stride + w2_column] = dst;
+}
+
+void Q4Matrix::make_sequential(const uint32_t* cpu_g_idx)
+{
+ uint32_t* cuda_new_qweight = NULL;
+ cudaMalloc(&cuda_new_qweight, height / 8 * width * sizeof(uint32_t));
+ cudaMalloc(&cuda_x_map, height * sizeof(uint32_t)); // TODO: Should probably be allocated in PyTorch
+
+ uint32_t* cpu_g_idx_map = (uint32_t*) calloc(groups, sizeof(uint32_t));
+ uint32_t* cpu_x_map = (uint32_t*) malloc(height * sizeof(uint32_t));
+ uint32_t* cpu_x_map_inv = (uint32_t*) malloc(height * sizeof(uint32_t));
+
+ // Group histogram
+
+ for (int i = 0; i < height; i++) cpu_g_idx_map[cpu_g_idx[i]]++;
+
+ // Group map
+
+ for (int i = 0, acc = 0; i < groups; i++)
+ {
+ short tmp = cpu_g_idx_map[i];
+ cpu_g_idx_map[i] = acc;
+ acc += tmp;
+ }
+
+ // X map (inverse)
+
+ for (int row = 0; row < height; row++)
+ {
+ uint32_t target_group = cpu_g_idx[row];
+ uint32_t target_row = cpu_g_idx_map[target_group];
+ cpu_g_idx_map[target_group]++;
+ cpu_x_map_inv[row] = target_row;
+ }
+
+ // X map
+
+ for (int row = 0; row < height; row++) cpu_x_map[cpu_x_map_inv[row]] = row;
+
+ // Move to CUDA
+
+ cudaMemcpyAsync(cuda_x_map, cpu_x_map, height * sizeof(uint32_t), cudaMemcpyHostToDevice);
+
+ // Rearrange rows in w
+
+ dim3 threads(UNSHUF_BLOCKSIZE_X, 1, 1);
+ dim3 blocks
+ (
+ (width + UNSHUF_BLOCKSIZE_X * 2 - 1) / (UNSHUF_BLOCKSIZE_X * 2),
+ height / 8,
+ 1
+ );
+
+ make_sequential_kernel<<>>(cuda_qweight, cuda_new_qweight, cuda_x_map, height / 8, width);
+
+ // Replace qweights
+
+ cudaMemcpyAsync(cuda_qweight, cuda_new_qweight, height / 8 * width * sizeof(uint32_t), cudaMemcpyDeviceToDevice);
+
+ // Cleanup
+
+ cudaDeviceSynchronize();
+ cudaFree(cuda_new_qweight);
+ free(cpu_g_idx_map);
+ free(cpu_x_map);
+ free(cpu_x_map_inv);
+}
+
+__global__ void reconstruct_kernel
+(
+ const uint32_t* __restrict__ w,
+ half* __restrict__ out, // (y)
+ const half* __restrict__ w_scales,
+ const uint32_t* __restrict__ w_zeros,
+ const int height,
+ const int width,
+ const int groupsize
+)
+{
+ // Start of block
+
+ int column = RECONS_THREADS_X * blockIdx.x + threadIdx.x;
+ int row = (RECONS_THREADS_Y * blockIdx.y + threadIdx.y) * 8;
+ if (column >= width) return;
+
+ // Views
+
+ MatrixView_q4_column w_(w, height, width);
+ MatrixView_half_rw out_(out, height, width);
+ MatrixView_half w_scales_(w_scales, height / groupsize, width);
+ MatrixView_q4_row w_zeros_(w_zeros, height / groupsize, width);
+
+ // Groupsize version
+
+ int group = row / groupsize;
+
+ half w_scale = w_scales_.item(group, column);
+ uint32_t w_zero = (w_zeros_.item(group, column) + 1) & 0x0f; // Avoid overflows.
+
+ uint32_t w_read = w_.item_uint32_t(row, column);
+ half* out_ptr = out_.item_ptr(row, column);
+
+ #pragma unroll
+ for (int s = 0; s < 32; s += 4)
+ {
+ half w_item = __hmul(__int2half_rn((int)((w_read >> s) & 0x0f) - w_zero), w_scale);
+ *out_ptr = w_item; out_ptr += out_.width;
+ }
+}
+
+void Q4Matrix::reconstruct(half* out)
+{
+ dim3 threads(RECONS_THREADS_X, RECONS_THREADS_Y, 1);
+
+ dim3 blocks
+ (
+ (width + threads.x - 1) / threads.x,
+ (height / 8 + threads.y - 1) / threads.y,
+ 1
+ );
+
+ reconstruct_kernel<<>>(cuda_qweight, out, cuda_scales, cuda_qzeros, height / 8, width, groupsize);
+}
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/q4_matrix.cuh b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/q4_matrix.cuh
new file mode 100644
index 0000000000000000000000000000000000000000..50cb72a41518593f6be4dded4f03c61772ef2ef9
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/cuda_func/q4_matrix.cuh
@@ -0,0 +1,53 @@
+// Adapted from turboderp exllama: https://github.com/turboderp/exllama
+
+#ifndef _q4_matrix_cuh
+#define _q4_matrix_cuh
+
+#include
+#include
+#include
+
+class Q4Matrix
+{
+public:
+
+ int device;
+
+ int height;
+ int width;
+ int groups;
+ int groupsize;
+
+ uint32_t* cuda_qweight = NULL;
+ uint32_t* cuda_qzeros = NULL;
+ half* cuda_scales = NULL;
+ uint32_t* cuda_x_map = NULL;
+
+ Q4Matrix
+ (
+ const int _height,
+ const int _width,
+ const int _groups,
+
+ uint32_t* _qweight,
+ uint32_t* _qzeros,
+ half* _scales,
+ uint32_t* _g_idx,
+
+ const int _device
+ );
+
+ ~Q4Matrix();
+
+ void reconstruct(half* out);
+
+private:
+
+ void make_sequential(const uint32_t* cpu_g_idx);
+
+};
+
+void g_q4_keep_matrix(Q4Matrix* m);
+void g_q4_free_matrices();
+
+#endif
\ No newline at end of file
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/exllama_ext.cpp b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/exllama_ext.cpp
new file mode 100644
index 0000000000000000000000000000000000000000..020fee4e124b61568277821ba1d92f1bf6443839
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/exllama_ext.cpp
@@ -0,0 +1,260 @@
+// Adapted from turboderp exllama: https://github.com/turboderp/exllama
+
+#include
+#include
+#include
+#include
+#include
+#include
+#include
+#include "util.cuh"
+#include "tuning.h"
+#include "cuda_buffers.cuh"
+#include "cuda_func/q4_matrix.cuh"
+#include "cuda_func/q4_matmul.cuh"
+#include "cuda_func/column_remap.cuh"
+
+#include
+#include
+#include
+
+// Check CUDA return code. We don't want to include Torch headers in the .cu files because parsing them adds almost a
+// minute to the compile time on a 12900K. Also passing exceptions back to Python is super tricky, so in place of
+// exceptions, CUDA functions return with a cudaError_t which we can parse and dump to the console.
+
+void check_cuda(cudaError_t ret)
+{
+ switch (ret)
+ {
+ case cudaSuccess:
+ break;
+
+ case cudaUnspecified:
+ printf(" **** Unspecified error\n");
+ TORCH_CHECK(false, "CUDA error");
+ break;
+
+ default:
+ printf(" **** CUDA error\n"); \
+ printf(" **** %s\n", cudaGetErrorString(ret)); \
+ TORCH_CHECK(false, "CUDA error"); \
+ break;
+ }
+}
+
+// Some decluttering macros
+
+#define STRINGIFY_(__x) #__x
+#define STRINGIFY(__x) STRINGIFY_(__x)
+#define TORCH_CHECK_DTYPE(__x, __dtype) TORCH_CHECK((__x).dtype() == torch::__dtype, #__x " is incorrect datatype, must be " #__dtype)
+#define TORCH_CHECK_DTYPE_OPT(__x, __dtype) TORCH_CHECK((__x).device().is_meta() || (__x).dtype() == torch::__dtype, #__x " is incorrect datatype, must be " #__dtype)
+#define TORCH_CHECK_SHAPES(__x, __dim_x, __y, __dim_y, __scale_y) TORCH_CHECK((__x).size(__dim_x) == (__y).size(__dim_y) * __scale_y, #__x " and " #__y " have incompatible shapes")
+#define TORCH_CHECK_SHAPES_OPT(__x, __dim_x, __y, __dim_y, __scale_y) TORCH_CHECK((__x).device().is_meta() || (__x).size(__dim_x) == (__y).size(__dim_y) * __scale_y, #__x " and " #__y " have incompatible shapes")
+#define TORCH_CHECK_SHAPE_MOD(__x, __dim_x, __mod) TORCH_CHECK((__x).size(__dim_x) % __mod == 0, #__x ".shape[" STRINGIFY(__dim_x) "] must be a multiple of " STRINGIFY(__mod))
+#define TORCH_CHECK_BUFFER_SIZE(__buffer, __minimum_size) TORCH_CHECK((__buffer).numel() >= __minimum_size, #__buffer " is too small")
+
+#define TORCH_CHECK_DEVICE_INDEX(__index) \
+do { \
+ TORCH_CHECK(__index >= 0, "no device index"); \
+ TORCH_CHECK(__index < CUDA_MAX_DEVICES, "invalid device index"); \
+} while(0)
+
+#define TORCH_CHECK_QUANT(__w, __w_scales, __w_zeros, __seq_g_idx, __x_map) \
+do { \
+ TORCH_CHECK_DTYPE(__w, kInt); \
+ TORCH_CHECK_DTYPE(__w_scales, kHalf); \
+ TORCH_CHECK_DTYPE(__w_zeros, kInt); \
+ TORCH_CHECK_DTYPE_OPT(__seq_g_idx, kShort); \
+ TORCH_CHECK_DTYPE_OPT(__x_map, kInt); \
+ TORCH_CHECK_SHAPES_OPT(__seq_g_idx, 0, __w, 0, 2 * 8); \
+ TORCH_CHECK_SHAPES_OPT(__x_map, 0, __w, 0, 8); \
+} while(0)
+
+int get_groupsize(torch::Tensor w, torch::Tensor w_zeros)
+{
+ int groupsize = w.size(0) * 8 / w_zeros.size(0);
+ TORCH_CHECK(groupsize * w_zeros.size(0) == w.size(0) * 8, "w.shape[-2] must be a multiple of zeros.shape[-2]")
+ return groupsize;
+}
+
+
+// Tuning parameters
+
+ExLlamaTuning tuningParams;
+
+void set_tuning_params
+(
+ int matmul_recons_thd,
+ bool matmul_fused_remap,
+ bool matmul_no_half2
+)
+{
+ tuningParams.matmul_recons_thd = matmul_recons_thd;
+ tuningParams.matmul_fused_remap = matmul_fused_remap;
+ tuningParams.matmul_no_half2 = matmul_no_half2;
+}
+
+
+// Release all unmanaged objects allocated by the extension
+
+void cleanup()
+{
+ cleanup_buffers_cuda();
+ g_q4_free_matrices();
+}
+
+
+// Prepare buffers for forward pass
+
+void prepare_buffers
+(
+ torch::Device device,
+ torch::Tensor temp_state,
+ torch::Tensor temp_dq
+)
+{
+ int device_index = device.index();
+ TORCH_CHECK_DEVICE_INDEX(device_index);
+ const at::cuda::OptionalCUDAGuard device_guard(device);
+ const long max_int = std::numeric_limits::max();
+
+ prepare_buffers_cuda
+ (
+ device_index,
+ // buffer size used for sanity checks
+ std::clamp((long)temp_state.numel(), (long)0, max_int),
+ (half*) temp_state.data_ptr(),
+ (half*) temp_dq.data_ptr()
+ );
+}
+
+
+// Create Q4Matrix, return handle
+
+uintptr_t make_q4
+(
+ torch::Tensor qweight,
+ torch::Tensor qzeros,
+ torch::Tensor scales,
+ torch::Tensor g_idx,
+ int device
+)
+{
+ TORCH_CHECK_DTYPE(qweight, kInt);
+ TORCH_CHECK_DTYPE(qzeros, kInt);
+ TORCH_CHECK_DTYPE(scales, kHalf);
+ TORCH_CHECK_DTYPE_OPT(g_idx, kInt);
+ TORCH_CHECK_SHAPES(qweight, 1, qzeros, 1, 8);
+ TORCH_CHECK_SHAPES(scales, 1, qweight, 1, 1);
+ TORCH_CHECK_SHAPES(qzeros, 0, scales, 0, 1);
+
+ int width = qweight.size(1);
+ int height = qweight.size(0) * 8;
+ int groups = qzeros.size(0);
+
+ Q4Matrix* m = new Q4Matrix
+ (
+ height,
+ width,
+ groups,
+
+ (uint32_t*) qweight.data_ptr(),
+ (uint32_t*) qzeros.data_ptr(),
+ (half*) scales.data_ptr(),
+ g_idx.device().is_meta() ? NULL : (uint32_t*) g_idx.data_ptr(),
+
+ device
+ );
+
+ g_q4_keep_matrix(m);
+ return reinterpret_cast (m);
+}
+
+
+// Matmul half @ quant -> half
+
+void q4_matmul
+(
+ torch::Tensor x,
+ uintptr_t w,
+ torch::Tensor out
+)
+{
+ Q4Matrix* wm = reinterpret_cast (w);
+
+ TORCH_CHECK_DTYPE(x, kHalf);
+ TORCH_CHECK_DTYPE(out, kHalf);
+ TORCH_CHECK_SHAPES(x, 0, out, 0, 1);
+ TORCH_CHECK(wm->height == x.size(-1), "x and w have incompatible shapes")
+
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(x));
+
+ int x_height = x.size(0);
+
+ if (tuningParams.matmul_recons_thd == 0 || x_height < tuningParams.matmul_recons_thd)
+ {
+ q4_matmul_cuda
+ (
+ &tuningParams,
+ (half*) x.data_ptr(),
+ x_height,
+ wm,
+ (half*) out.data_ptr()
+ );
+ }
+ else
+ {
+ q4_matmul_recons_cuda
+ (
+ &tuningParams,
+ (half*) x.data_ptr(),
+ x_height,
+ wm,
+ (half*) out.data_ptr(),
+ at::cuda::getCurrentCUDABlasHandle()
+ );
+ }
+}
+
+
+// Remap columns in half tensor
+
+void column_remap
+(
+ torch::Tensor x,
+ torch::Tensor x_new,
+ torch::Tensor x_map
+)
+{
+ TORCH_CHECK_DTYPE(x, kHalf);
+ TORCH_CHECK_DTYPE(x_new, kHalf);
+ TORCH_CHECK_DTYPE(x_map, kInt);
+ TORCH_CHECK_SHAPES(x_map, 0, x, 1, 1);
+
+ int height = x.size(0);
+ int width = x.size(1);
+
+ TORCH_CHECK_BUFFER_SIZE(x_new, height * width);
+
+ const at::cuda::OptionalCUDAGuard device_guard(device_of(x));
+
+ column_remap_cuda
+ (
+ (half*) x.data_ptr(),
+ (half*) x_new.data_ptr(),
+ height,
+ width,
+ (uint32_t*) x_map.data_ptr()
+ );
+}
+
+
+PYBIND11_MODULE(TORCH_EXTENSION_NAME, m)
+{
+ m.def("set_tuning_params", &set_tuning_params, "set_tuning_params");
+ m.def("prepare_buffers", &prepare_buffers, "prepare_buffers");
+ m.def("cleanup", &cleanup, "cleanup");
+ m.def("make_q4", &make_q4, "make_q4");
+ m.def("q4_matmul", &q4_matmul, "q4_matmul");
+ m.def("cleanup_buffers_cuda", &cleanup_buffers_cuda, "cleanup_buffers_cuda");
+}
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/hip_compat.cuh b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/hip_compat.cuh
new file mode 100644
index 0000000000000000000000000000000000000000..680274787bbfcf6720d2db343b01437a066ce667
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/hip_compat.cuh
@@ -0,0 +1,53 @@
+// Adapted from turboderp exllama: https://github.com/turboderp/exllama
+
+#ifndef _hip_compat_cuh
+#define _hip_compat_cuh
+
+// Workaround for a bug in hipamd, backported from upstream, this is fixed in ROCm 5.6.
+__device__ __forceinline__ __half __compat_hrcp(__half x) {
+ return __half_raw{
+ static_cast<_Float16>(__builtin_amdgcn_rcph(static_cast<__half_raw>(x).data))};
+}
+
+// ROCm 6.0 compatible from: /opt/rocm-6.0.0/include/hip/amd_detail/amd_hip_fp16.h:1708
+__device__ __forceinline__ __half2 __compat_h2rcp(__half2 x) {
+ return _Float16_2{
+ _Float16_2{static_cast<_Float16>(1.0f),
+ static_cast<_Float16>(1.0f)} / x.data};
+}
+
+#define hrcp __compat_hrcp
+#define h2rcp __compat_h2rcp
+
+// Automatic conversion of hipblasHgemm doesn't convert half to hipblasHalf.
+__host__ __forceinline__ hipblasStatus_t __compat_hipblasHgemm(hipblasHandle_t handle,
+ hipblasOperation_t transA,
+ hipblasOperation_t transB,
+ int m,
+ int n,
+ int k,
+ const half* alpha,
+ const half* AP,
+ int lda,
+ const half* BP,
+ int ldb,
+ const half* beta,
+ half* CP,
+ int ldc) {
+ return hipblasHgemm(handle, transA, transB, m, n, k,
+ reinterpret_cast(alpha),
+ reinterpret_cast(AP), lda,
+ reinterpret_cast(BP), ldb,
+ reinterpret_cast(beta),
+ reinterpret_cast(CP), ldc);
+}
+#define hipblasHgemm __compat_hipblasHgemm
+
+// Previous version of PyTorch were converting to rocBLAS instead of hipBLAS.
+#define rocblas_handle hipblasHandle_t
+#define rocblas_operation_none HIPBLAS_OP_N
+#define rocblas_get_stream hipblasGetStream
+#define rocblas_set_stream hipblasSetStream
+#define rocblas_hgemm __compat_hipblasHgemm
+
+#endif
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/matrix.cuh b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/matrix.cuh
new file mode 100644
index 0000000000000000000000000000000000000000..2fd5ab0b36cd0dd67c9b6081740bbed12711ee09
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/matrix.cuh
@@ -0,0 +1,294 @@
+// Adapted from turboderp exllama: https://github.com/turboderp/exllama
+
+#ifndef _matrix_cuh
+#define _matrix_cuh
+
+#include
+#include
+
+class MatrixView_half
+{
+public:
+ const half* data;
+ const int height;
+ const int width;
+
+ __device__ __forceinline__ MatrixView_half(const half* data, const int height, const int width)
+ : data(data), height(height), width(width)
+ { }
+
+ __device__ __forceinline__ half item(int row, int column) const { return data[row * width + column]; }
+ __device__ __forceinline__ half2 item_half2(int row, int column) const { return ((half2*)data)[(row * width + column) / 2]; }
+ __device__ __forceinline__ half2 item_half2half2(int row, int column) const { return __half2half2(data[row * width + column]); }
+ __device__ __forceinline__ const half* item_ptr(int row, int column) const { return &data[row * width + column]; }
+};
+
+class MatrixView_half_rw
+{
+public:
+ half* data;
+ const int height;
+ const int width;
+
+ __device__ __forceinline__ MatrixView_half_rw(half* data, const int height, const int width)
+ : data(data), height(height), width(width)
+ { }
+
+ __device__ __forceinline__ half item(int row, int column) const { return data[row * width + column]; }
+ __device__ __forceinline__ half2 item_half2(int row, int column) const { return ((half2*)data)[(row * width + column) / 2]; }
+ __device__ __forceinline__ half* item_ptr(int row, int column) { return &data[row * width + column]; }
+ __device__ __forceinline__ void set(int row, int column, half value) { data[row * width + column] = value; }
+ __device__ __forceinline__ void set_half2(int row, int column, half2 value) { ((half2*)data)[(row * width + column) / 2] = value; }
+};
+
+class MatrixView_q4_row
+{
+public:
+ const uint32_t* data;
+ const int height;
+ const int width;
+
+ __device__ __forceinline__ MatrixView_q4_row(const uint32_t* data, const int height, const int width)
+ : data(data), height(height), width(width)
+ { }
+
+ __device__ __forceinline__ int item(int row, int column) const
+ {
+ int shift = (column & 0x07) * 4;
+ return (data[row * width / 8 + column / 8] >> shift) & 0x0f;
+ }
+};
+
+class MatrixView_q4_column
+{
+public:
+ const uint32_t* data;
+ const int height;
+ const int width;
+
+ __device__ __forceinline__ MatrixView_q4_column(const uint32_t* data, const int height, const int width)
+ : data(data), height(height), width(width)
+ { }
+
+ __device__ __forceinline__ int item(int row, int column) const
+ {
+ int shift = (row & 0x07) * 4;
+ return (data[row / 8 * width + column] >> shift) & 0x0f;
+ }
+
+ __device__ __forceinline__ uint32_t item_uint32_t(int row, int column) { return data[row / 8 * width + column]; }
+ __device__ __forceinline__ const uint32_t* item_uint32_ptr(int row, int column) { return &data[row / 8 * width + column]; }
+};
+
+// TODO: Rewrite all these dot product functions using functors or something, move to q4_matmul.cu
+
+// Accumulated dot product of 8-element row vectors in h and quantized column vectors in v, constant zero/scale
+
+__device__ __forceinline__ half2 dot_product_8
+(
+ const half2 acc,
+ MatrixView_half& h_,
+ const int h_row,
+ const int h_column, // divisible by 8
+ MatrixView_q4_column& v_,
+ const int v_row, // divisible by 8
+ const int v_column,
+ const half2 v_scale_2,
+ const uint32_t v_zero, // + 1 (!!)
+ const int count
+)
+{
+ const half2* h_ptr = (const half2*) h_.item_ptr(h_row, h_column);
+ const uint32_t* v_ptr = (const uint32_t*) v_.item_uint32_ptr(v_row, v_column);
+ half2 result = acc;
+
+ for (int i = 0; i < count; i++)
+ {
+ uint32_t v_read = *v_ptr; v_ptr += v_.width;
+
+ half v_0 = __int2half_rn((int)((v_read ) & 0x0f) - v_zero);
+ half v_1 = __int2half_rn((int)((v_read >> 4) & 0x0f) - v_zero);
+ half v_2 = __int2half_rn((int)((v_read >> 8) & 0x0f) - v_zero);
+ half v_3 = __int2half_rn((int)((v_read >> 12) & 0x0f) - v_zero);
+ half v_4 = __int2half_rn((int)((v_read >> 16) & 0x0f) - v_zero);
+ half v_5 = __int2half_rn((int)((v_read >> 20) & 0x0f) - v_zero);
+ half v_6 = __int2half_rn((int)((v_read >> 24) & 0x0f) - v_zero);
+ half v_7 = __int2half_rn((int)((v_read >> 28) ) - v_zero);
+
+ half2 v_01 = __halves2half2(v_0, v_1);
+ half2 v_23 = __halves2half2(v_2, v_3);
+ half2 v_45 = __halves2half2(v_4, v_5);
+ half2 v_67 = __halves2half2(v_6, v_7);
+
+// half2 v_01 = q4_table[v_zero - 1][(v_read ) & 0xff]; // (constant memory is too slow apparently)
+// half2 v_23 = q4_table[v_zero - 1][(v_read >> 8) & 0xff];
+// half2 v_45 = q4_table[v_zero - 1][(v_read >> 16) & 0xff];
+// half2 v_67 = q4_table[v_zero - 1][(v_read >> 24) ];
+
+ half2 tmp = __hmul2(*h_ptr++, v_01);
+ tmp = __hfma2(*h_ptr++, v_23, tmp);
+ tmp = __hfma2(*h_ptr++, v_45, tmp);
+ tmp = __hfma2(*h_ptr++, v_67, tmp);
+ result = __hfma2(v_scale_2, tmp, result);
+ }
+
+ return result;
+}
+
+__device__ __forceinline__ half dot_product_8_h
+(
+ const half acc,
+ MatrixView_half& h_,
+ const int h_row,
+ const int h_column, // divisible by 8
+ MatrixView_q4_column& v_,
+ const int v_row, // divisible by 8
+ const int v_column,
+ const half v_scale,
+ const uint32_t v_zero, // + 1 (!!)
+ const int count
+)
+{
+ const half* h_ptr = h_.item_ptr(h_row, h_column);
+ const uint32_t* v_ptr = (const uint32_t*) v_.item_uint32_ptr(v_row, v_column);
+ half result = acc;
+
+ for (int i = 0; i < count; i++)
+ {
+ uint32_t v_read = *v_ptr; v_ptr += v_.width;
+
+ half v_0 = __int2half_rn((int)((v_read ) & 0x0f) - v_zero);
+ half v_1 = __int2half_rn((int)((v_read >> 4) & 0x0f) - v_zero);
+ half v_2 = __int2half_rn((int)((v_read >> 8) & 0x0f) - v_zero);
+ half v_3 = __int2half_rn((int)((v_read >> 12) & 0x0f) - v_zero);
+ half v_4 = __int2half_rn((int)((v_read >> 16) & 0x0f) - v_zero);
+ half v_5 = __int2half_rn((int)((v_read >> 20) & 0x0f) - v_zero);
+ half v_6 = __int2half_rn((int)((v_read >> 24) & 0x0f) - v_zero);
+ half v_7 = __int2half_rn((int)((v_read >> 28) ) - v_zero);
+
+ half tmp = __hmul(*h_ptr++, v_0);
+ tmp = __hfma(*h_ptr++, v_1, tmp);
+ tmp = __hfma(*h_ptr++, v_2, tmp);
+ tmp = __hfma(*h_ptr++, v_3, tmp);
+ tmp = __hfma(*h_ptr++, v_4, tmp);
+ tmp = __hfma(*h_ptr++, v_5, tmp);
+ tmp = __hfma(*h_ptr++, v_6, tmp);
+ tmp = __hfma(*h_ptr++, v_7, tmp);
+ result = __hfma(v_scale, tmp, result);
+ }
+
+ return result;
+}
+
+// Accumulated dot product of 8-element row vectors in h and quantized column vectors in v, constant zero/scale, with x_map
+
+__device__ __forceinline__ half2 dot_product_8_x_map
+(
+ const half2 acc,
+ MatrixView_half& h_,
+ const int h_row,
+ const int h_column, // divisible by 8
+ MatrixView_q4_column& v_,
+ const int v_row, // divisible by 8
+ const int v_column,
+ const half2 v_scale_2,
+ const uint32_t v_zero, // + 1 (!!)
+ const int count,
+ const uint32_t* x_map
+)
+{
+ const half* h_ptr = h_.item_ptr(h_row, 0);
+ const uint32_t* x_map_ptr = x_map + h_column;
+ const uint32_t* v_ptr = (const uint32_t*) v_.item_uint32_ptr(v_row, v_column);
+ half2 result = acc;
+
+ for (int i = 0; i < count; i++)
+ {
+ uint32_t v_read = *v_ptr; v_ptr += v_.width;
+
+ half v_0 = __int2half_rn((int)((v_read ) & 0x0f) - v_zero);
+ half v_1 = __int2half_rn((int)((v_read >> 4) & 0x0f) - v_zero);
+ half v_2 = __int2half_rn((int)((v_read >> 8) & 0x0f) - v_zero);
+ half v_3 = __int2half_rn((int)((v_read >> 12) & 0x0f) - v_zero);
+ half v_4 = __int2half_rn((int)((v_read >> 16) & 0x0f) - v_zero);
+ half v_5 = __int2half_rn((int)((v_read >> 20) & 0x0f) - v_zero);
+ half v_6 = __int2half_rn((int)((v_read >> 24) & 0x0f) - v_zero);
+ half v_7 = __int2half_rn((int)((v_read >> 28) ) - v_zero);
+
+ half2 v_01 = __halves2half2(v_0, v_1);
+ half2 v_23 = __halves2half2(v_2, v_3);
+ half2 v_45 = __halves2half2(v_4, v_5);
+ half2 v_67 = __halves2half2(v_6, v_7);
+
+ half h_0 = h_ptr[*x_map_ptr++];
+ half h_1 = h_ptr[*x_map_ptr++];
+ half h_2 = h_ptr[*x_map_ptr++];
+ half h_3 = h_ptr[*x_map_ptr++];
+ half h_4 = h_ptr[*x_map_ptr++];
+ half h_5 = h_ptr[*x_map_ptr++];
+ half h_6 = h_ptr[*x_map_ptr++];
+ half h_7 = h_ptr[*x_map_ptr++];
+
+ half2 h_01 = __halves2half2(h_0, h_1);
+ half2 h_23 = __halves2half2(h_2, h_3);
+ half2 h_45 = __halves2half2(h_4, h_5);
+ half2 h_67 = __halves2half2(h_6, h_7);
+
+ half2 tmp = __hmul2(h_01, v_01);
+ tmp = __hfma2(h_23, v_23, tmp);
+ tmp = __hfma2(h_45, v_45, tmp);
+ tmp = __hfma2(h_67, v_67, tmp);
+ result = __hfma2(v_scale_2, tmp, result);
+ }
+
+ return result;
+}
+
+__device__ __forceinline__ half dot_product_8_x_map_h
+(
+ const half acc,
+ MatrixView_half& h_,
+ const int h_row,
+ const int h_column, // divisible by 8
+ MatrixView_q4_column& v_,
+ const int v_row, // divisible by 8
+ const int v_column,
+ const half v_scale,
+ const uint32_t v_zero, // + 1 (!!)
+ const int count,
+ const uint32_t* x_map
+)
+{
+ const half* h_ptr = h_.item_ptr(h_row, 0);
+ const uint32_t* x_map_ptr = x_map + h_column;
+ const uint32_t* v_ptr = (const uint32_t*) v_.item_uint32_ptr(v_row, v_column);
+ half result = acc;
+
+ for (int i = 0; i < count; i++)
+ {
+ uint32_t v_read = *v_ptr; v_ptr += v_.width;
+
+ half v_0 = __int2half_rn((int)((v_read ) & 0x0f) - v_zero);
+ half v_1 = __int2half_rn((int)((v_read >> 4) & 0x0f) - v_zero);
+ half v_2 = __int2half_rn((int)((v_read >> 8) & 0x0f) - v_zero);
+ half v_3 = __int2half_rn((int)((v_read >> 12) & 0x0f) - v_zero);
+ half v_4 = __int2half_rn((int)((v_read >> 16) & 0x0f) - v_zero);
+ half v_5 = __int2half_rn((int)((v_read >> 20) & 0x0f) - v_zero);
+ half v_6 = __int2half_rn((int)((v_read >> 24) & 0x0f) - v_zero);
+ half v_7 = __int2half_rn((int)((v_read >> 28) ) - v_zero);
+
+ half tmp = __hmul(h_ptr[*x_map_ptr++], v_0);
+ tmp = __hfma(h_ptr[*x_map_ptr++], v_1, tmp);
+ tmp = __hfma(h_ptr[*x_map_ptr++], v_2, tmp);
+ tmp = __hfma(h_ptr[*x_map_ptr++], v_3, tmp);
+ tmp = __hfma(h_ptr[*x_map_ptr++], v_4, tmp);
+ tmp = __hfma(h_ptr[*x_map_ptr++], v_5, tmp);
+ tmp = __hfma(h_ptr[*x_map_ptr++], v_6, tmp);
+ tmp = __hfma(h_ptr[*x_map_ptr++], v_7, tmp);
+ result = __hfma(v_scale, tmp, result);
+ }
+
+ return result;
+}
+
+#endif
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/tuning.h b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/tuning.h
new file mode 100644
index 0000000000000000000000000000000000000000..770ca46aa7c8b38ac96438445f647bbb29a7ea2b
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/tuning.h
@@ -0,0 +1,13 @@
+// Adapted from turboderp exllama: https://github.com/turboderp/exllama
+
+#ifndef _tuning_h
+#define _tuning_h
+
+struct ExLlamaTuning
+{
+ int matmul_recons_thd;
+ bool matmul_fused_remap;
+ bool matmul_no_half2;
+};
+
+#endif
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/util.cuh b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/util.cuh
new file mode 100644
index 0000000000000000000000000000000000000000..7b397573214b2b1f1af50a82320f61aabee5c8f1
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllama/util.cuh
@@ -0,0 +1,33 @@
+// Adapted from turboderp exllama: https://github.com/turboderp/exllama
+
+#ifndef _util_cuh
+#define _util_cuh
+
+#include
+#include
+#include
+#include
+
+#if defined(USE_ROCM)
+#define cudaUnspecified hipErrorUnknown
+#else
+#define cudaUnspecified cudaErrorApiFailureBase
+#endif
+
+// React to failure on return code != cudaSuccess
+
+#define _cuda_check(fn) \
+do { \
+ {_cuda_err = fn;} \
+ if (_cuda_err != cudaSuccess) goto _cuda_fail; \
+} while(false)
+
+// React to failure on return code == 0
+
+#define _alloc_check(fn) \
+do { \
+ if (!(fn)) { _cuda_err = cudaUnspecified; goto _cuda_fail; } \
+ else _cuda_err = cudaSuccess; \
+} while(false)
+
+#endif
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllamav2/config.h b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllamav2/config.h
new file mode 100644
index 0000000000000000000000000000000000000000..86baaf4129d0d0f3415ba83ed73603403da6c6bc
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllamav2/config.h
@@ -0,0 +1,13 @@
+#ifndef _config_h
+#define _config_h
+
+#define MAX_Q_GEMM_ROWS 50
+
+#define QMODE_2BIT 1
+#define QMODE_3BIT 1
+#define QMODE_4BIT 1
+#define QMODE_5BIT 1
+#define QMODE_6BIT 0
+#define QMODE_8BIT 0
+
+#endif
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllamav2/cpp/util.h b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllamav2/cpp/util.h
new file mode 100644
index 0000000000000000000000000000000000000000..919703a89da8bb1124acd3a06fcbc76c3ce90d6a
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllamav2/cpp/util.h
@@ -0,0 +1,12 @@
+#ifndef _util_h
+#define _util_h
+
+#define DBGS(__x) printf("%s\n", __x)
+#define DBGI(__x) printf("%s: %i\n", #__x, __x)
+#define DBGI2(__x, __y) printf("%s, %s: %i, %i\n", #__x, #__y, __x, __y)
+#define DBGI3(__x, __y, __z) printf("%s, %s, %s: %i, %i, %i\n", #__x, #__y, #__z, __x, __y, __z)
+#define DBGF(__x) printf("%s: %f\n", #__x, __x)
+#define DBGF2(__x, __y) printf("%s, %s: %f, %f\n", #__x, #__y, __x, __y)
+#define DBGF3(__x, __y, __z) printf("%s, %s, %s: %f, %f, %f\n", #__x, #__y, #__z, __x, __y, __z)
+
+#endif
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllamav2/cuda/compat.cuh b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllamav2/cuda/compat.cuh
new file mode 100644
index 0000000000000000000000000000000000000000..12684ff8b59fe5daa272dd218ccf2a0170e87333
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllamav2/cuda/compat.cuh
@@ -0,0 +1,56 @@
+#ifndef _compat_cuh
+#define _compat_cuh
+
+// atomicAdd for half types, to support CC < 7.x
+
+__device__ __forceinline__ void atomicAdd_half(half* address, half val)
+{
+ unsigned int * address_as_ui = (unsigned int *) ((char *)address - ((size_t)address & 2));
+ unsigned int old = *address_as_ui;
+ unsigned int assumed;
+
+ do
+ {
+ assumed = old;
+ __half_raw hsum;
+ hsum.x = (size_t)address & 2 ? (old >> 16) : (old & 0xffff);
+ half tmpres = __hadd(hsum, val);
+ hsum = __half_raw(tmpres);
+ old = (size_t)address & 2 ? (old & 0xffff) | (hsum.x << 16) : (old & 0xffff0000) | hsum.x;
+ old = atomicCAS(address_as_ui, assumed, old);
+ }
+ while (assumed != old);
+}
+
+// atomicAdd for half2 types
+
+__device__ __forceinline__ void atomicAdd_half2(half2* address, half2 val)
+{
+ unsigned int* address_as_ui = (unsigned int*)address;
+ unsigned int old = *address_as_ui;
+ unsigned int assumed;
+ do
+ {
+ assumed = old;
+ half2 old_val = *((half2*)&old);
+ half2 new_val = __hadd2(old_val, val);
+ old = atomicCAS(address_as_ui, assumed, *((unsigned int*)&new_val));
+ }
+ while (assumed != old);
+}
+
+//
+
+#if defined(__CUDA_ARCH__) || defined(USE_ROCM)
+#if __CUDA_ARCH__ < 700 || defined(USE_ROCM)
+
+__device__ __forceinline__ void atomicAdd(half* address, half val) { atomicAdd_half(address, val); }
+
+#if __CUDA_ARCH__ < 600 || defined(USE_ROCM)
+__device__ __forceinline__ void atomicAdd(half2* address, half2 val) { atomicAdd_half2(address, val); }
+#endif
+
+#endif
+#endif
+
+#endif
diff --git a/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllamav2/cuda/compat_gemm.cuh b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllamav2/cuda/compat_gemm.cuh
new file mode 100644
index 0000000000000000000000000000000000000000..19b1e4a60416bc082189943eccbe710a10f3c82b
--- /dev/null
+++ b/lm-quant-toolkit/.deps/AutoGPTQ/autogptq_extension/exllamav2/cuda/compat_gemm.cuh
@@ -0,0 +1,38 @@
+#ifndef _compat_gemm_cuh
+#define _compat_gemm_cuh
+
+#if defined(USE_ROCM)
+
+// For some reason this include is not present anywhere in exllama_v2 codebase, but it is required
+// for symbols as hipblasHalf.
+#include