diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/flava.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/flava.md
new file mode 100644
index 0000000000000000000000000000000000000000..d9f9f1de514671af51dd83b7c30abcf1bbc2234f
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/flava.md
@@ -0,0 +1,103 @@
+
+
+# FLAVA
+
+## Overview
+
+The FLAVA model was proposed in [FLAVA: A Foundational Language And Vision Alignment Model](https://arxiv.org/abs/2112.04482) by Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, and Douwe Kiela and is accepted at CVPR 2022.
+
+The paper aims at creating a single unified foundation model which can work across vision, language
+as well as vision-and-language multimodal tasks.
+
+The abstract from the paper is the following:
+
+*State-of-the-art vision and vision-and-language models rely on large-scale visio-linguistic pretraining for obtaining good performance on a variety
+of downstream tasks. Generally, such models are often either cross-modal (contrastive) or multi-modal
+(with earlier fusion) but not both; and they often only target specific modalities or tasks. A promising
+direction would be to use a single holistic universal model, as a "foundation", that targets all modalities
+at once -- a true vision and language foundation model should be good at vision tasks, language tasks, and
+cross- and multi-modal vision and language tasks. We introduce FLAVA as such a model and demonstrate
+impressive performance on a wide range of 35 tasks spanning these target modalities.*
+
+This model was contributed by [aps](https://huggingface.co/aps). The original code can be found [here](https://github.com/facebookresearch/multimodal/tree/main/examples/flava).
+
+## FlavaConfig
+
+[[autodoc]] FlavaConfig
+
+## FlavaTextConfig
+
+[[autodoc]] FlavaTextConfig
+
+## FlavaImageConfig
+
+[[autodoc]] FlavaImageConfig
+
+## FlavaMultimodalConfig
+
+[[autodoc]] FlavaMultimodalConfig
+
+## FlavaImageCodebookConfig
+
+[[autodoc]] FlavaImageCodebookConfig
+
+## FlavaProcessor
+
+[[autodoc]] FlavaProcessor
+
+## FlavaFeatureExtractor
+
+[[autodoc]] FlavaFeatureExtractor
+
+## FlavaImageProcessor
+
+[[autodoc]] FlavaImageProcessor
+ - preprocess
+
+## FlavaForPreTraining
+
+[[autodoc]] FlavaForPreTraining
+ - forward
+
+## FlavaModel
+
+[[autodoc]] FlavaModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## FlavaImageCodebook
+
+[[autodoc]] FlavaImageCodebook
+ - forward
+ - get_codebook_indices
+ - get_codebook_probs
+
+## FlavaTextModel
+
+[[autodoc]] FlavaTextModel
+ - forward
+
+## FlavaImageModel
+
+[[autodoc]] FlavaImageModel
+ - forward
+
+## FlavaMultimodalModel
+
+[[autodoc]] FlavaMultimodalModel
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/fnet.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/fnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..1bcae678e632d9cd16b3d075e8da9f3de23e78b9
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/fnet.md
@@ -0,0 +1,110 @@
+
+
+# FNet
+
+## Overview
+
+The FNet model was proposed in [FNet: Mixing Tokens with Fourier Transforms](https://arxiv.org/abs/2105.03824) by
+James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon. The model replaces the self-attention layer in a BERT
+model with a fourier transform which returns only the real parts of the transform. The model is significantly faster
+than the BERT model because it has fewer parameters and is more memory efficient. The model achieves about 92-97%
+accuracy of BERT counterparts on GLUE benchmark, and trains much faster than the BERT model. The abstract from the
+paper is the following:
+
+*We show that Transformer encoder architectures can be sped up, with limited accuracy costs, by replacing the
+self-attention sublayers with simple linear transformations that "mix" input tokens. These linear mixers, along with
+standard nonlinearities in feed-forward layers, prove competent at modeling semantic relationships in several text
+classification tasks. Most surprisingly, we find that replacing the self-attention sublayer in a Transformer encoder
+with a standard, unparameterized Fourier Transform achieves 92-97% of the accuracy of BERT counterparts on the GLUE
+benchmark, but trains 80% faster on GPUs and 70% faster on TPUs at standard 512 input lengths. At longer input lengths,
+our FNet model is significantly faster: when compared to the "efficient" Transformers on the Long Range Arena
+benchmark, FNet matches the accuracy of the most accurate models, while outpacing the fastest models across all
+sequence lengths on GPUs (and across relatively shorter lengths on TPUs). Finally, FNet has a light memory footprint
+and is particularly efficient at smaller model sizes; for a fixed speed and accuracy budget, small FNet models
+outperform Transformer counterparts.*
+
+This model was contributed by [gchhablani](https://huggingface.co/gchhablani). The original code can be found [here](https://github.com/google-research/google-research/tree/master/f_net).
+
+## Usage tips
+
+The model was trained without an attention mask as it is based on Fourier Transform. The model was trained with
+maximum sequence length 512 which includes pad tokens. Hence, it is highly recommended to use the same maximum
+sequence length for fine-tuning and inference.
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## FNetConfig
+
+[[autodoc]] FNetConfig
+
+## FNetTokenizer
+
+[[autodoc]] FNetTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## FNetTokenizerFast
+
+[[autodoc]] FNetTokenizerFast
+
+## FNetModel
+
+[[autodoc]] FNetModel
+ - forward
+
+## FNetForPreTraining
+
+[[autodoc]] FNetForPreTraining
+ - forward
+
+## FNetForMaskedLM
+
+[[autodoc]] FNetForMaskedLM
+ - forward
+
+## FNetForNextSentencePrediction
+
+[[autodoc]] FNetForNextSentencePrediction
+ - forward
+
+## FNetForSequenceClassification
+
+[[autodoc]] FNetForSequenceClassification
+ - forward
+
+## FNetForMultipleChoice
+
+[[autodoc]] FNetForMultipleChoice
+ - forward
+
+## FNetForTokenClassification
+
+[[autodoc]] FNetForTokenClassification
+ - forward
+
+## FNetForQuestionAnswering
+
+[[autodoc]] FNetForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/focalnet.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/focalnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..c4c97980f069767207c03d191f61c70de3c8acad
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/focalnet.md
@@ -0,0 +1,50 @@
+
+
+# FocalNet
+
+## Overview
+
+The FocalNet model was proposed in [Focal Modulation Networks](https://arxiv.org/abs/2203.11926) by Jianwei Yang, Chunyuan Li, Xiyang Dai, Lu Yuan, Jianfeng Gao.
+FocalNets completely replace self-attention (used in models like [ViT](vit) and [Swin](swin)) by a focal modulation mechanism for modeling token interactions in vision.
+The authors claim that FocalNets outperform self-attention based models with similar computational costs on the tasks of image classification, object detection, and segmentation.
+
+The abstract from the paper is the following:
+
+*We propose focal modulation networks (FocalNets in short), where self-attention (SA) is completely replaced by a focal modulation mechanism for modeling token interactions in vision. Focal modulation comprises three components: (i) hierarchical contextualization, implemented using a stack of depth-wise convolutional layers, to encode visual contexts from short to long ranges, (ii) gated aggregation to selectively gather contexts for each query token based on its
+content, and (iii) element-wise modulation or affine transformation to inject the aggregated context into the query. Extensive experiments show FocalNets outperform the state-of-the-art SA counterparts (e.g., Swin and Focal Transformers) with similar computational costs on the tasks of image classification, object detection, and segmentation. Specifically, FocalNets with tiny and base size achieve 82.3% and 83.9% top-1 accuracy on ImageNet-1K. After pretrained on ImageNet-22K in 224 resolution, it attains 86.5% and 87.3% top-1 accuracy when finetuned with resolution 224 and 384, respectively. When transferred to downstream tasks, FocalNets exhibit clear superiority. For object detection with Mask R-CNN, FocalNet base trained with 1\times outperforms the Swin counterpart by 2.1 points and already surpasses Swin trained with 3\times schedule (49.0 v.s. 48.5). For semantic segmentation with UPerNet, FocalNet base at single-scale outperforms Swin by 2.4, and beats Swin at multi-scale (50.5 v.s. 49.7). Using large FocalNet and Mask2former, we achieve 58.5 mIoU for ADE20K semantic segmentation, and 57.9 PQ for COCO Panoptic Segmentation. Using huge FocalNet and DINO, we achieved 64.3 and 64.4 mAP on COCO minival and test-dev, respectively, establishing new SoTA on top of much larger attention-based models like Swinv2-G and BEIT-3.*
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/microsoft/FocalNet).
+
+## FocalNetConfig
+
+[[autodoc]] FocalNetConfig
+
+## FocalNetModel
+
+[[autodoc]] FocalNetModel
+ - forward
+
+## FocalNetForMaskedImageModeling
+
+[[autodoc]] FocalNetForMaskedImageModeling
+ - forward
+
+## FocalNetForImageClassification
+
+[[autodoc]] FocalNetForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/fsmt.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/fsmt.md
new file mode 100644
index 0000000000000000000000000000000000000000..9419dce71edf38d4a287fb429c2525b95abe9dbe
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/fsmt.md
@@ -0,0 +1,64 @@
+
+
+# FSMT
+
+## Overview
+
+FSMT (FairSeq MachineTranslation) models were introduced in [Facebook FAIR's WMT19 News Translation Task Submission](https://arxiv.org/abs/1907.06616) by Nathan Ng, Kyra Yee, Alexei Baevski, Myle Ott, Michael Auli, Sergey Edunov.
+
+The abstract of the paper is the following:
+
+*This paper describes Facebook FAIR's submission to the WMT19 shared news translation task. We participate in two
+language pairs and four language directions, English <-> German and English <-> Russian. Following our submission from
+last year, our baseline systems are large BPE-based transformer models trained with the Fairseq sequence modeling
+toolkit which rely on sampled back-translations. This year we experiment with different bitext data filtering schemes,
+as well as with adding filtered back-translated data. We also ensemble and fine-tune our models on domain-specific
+data, then decode using noisy channel model reranking. Our submissions are ranked first in all four directions of the
+human evaluation campaign. On En->De, our system significantly outperforms other systems as well as human translations.
+This system improves upon our WMT'18 submission by 4.5 BLEU points.*
+
+This model was contributed by [stas](https://huggingface.co/stas). The original code can be found
+[here](https://github.com/pytorch/fairseq/tree/master/examples/wmt19).
+
+## Implementation Notes
+
+- FSMT uses source and target vocabulary pairs that aren't combined into one. It doesn't share embeddings tokens
+ either. Its tokenizer is very similar to [`XLMTokenizer`] and the main model is derived from
+ [`BartModel`].
+
+
+## FSMTConfig
+
+[[autodoc]] FSMTConfig
+
+## FSMTTokenizer
+
+[[autodoc]] FSMTTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## FSMTModel
+
+[[autodoc]] FSMTModel
+ - forward
+
+## FSMTForConditionalGeneration
+
+[[autodoc]] FSMTForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/funnel.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/funnel.md
new file mode 100644
index 0000000000000000000000000000000000000000..d6929691f40038682addb14501350f7ca1eea13b
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/funnel.md
@@ -0,0 +1,185 @@
+
+
+# Funnel Transformer
+
+
+
+
+## Overview
+
+The Funnel Transformer model was proposed in the paper [Funnel-Transformer: Filtering out Sequential Redundancy for
+Efficient Language Processing](https://arxiv.org/abs/2006.03236). It is a bidirectional transformer model, like
+BERT, but with a pooling operation after each block of layers, a bit like in traditional convolutional neural networks
+(CNN) in computer vision.
+
+The abstract from the paper is the following:
+
+*With the success of language pretraining, it is highly desirable to develop more efficient architectures of good
+scalability that can exploit the abundant unlabeled data at a lower cost. To improve the efficiency, we examine the
+much-overlooked redundancy in maintaining a full-length token-level presentation, especially for tasks that only
+require a single-vector presentation of the sequence. With this intuition, we propose Funnel-Transformer which
+gradually compresses the sequence of hidden states to a shorter one and hence reduces the computation cost. More
+importantly, by re-investing the saved FLOPs from length reduction in constructing a deeper or wider model, we further
+improve the model capacity. In addition, to perform token-level predictions as required by common pretraining
+objectives, Funnel-Transformer is able to recover a deep representation for each token from the reduced hidden sequence
+via a decoder. Empirically, with comparable or fewer FLOPs, Funnel-Transformer outperforms the standard Transformer on
+a wide variety of sequence-level prediction tasks, including text classification, language understanding, and reading
+comprehension.*
+
+This model was contributed by [sgugger](https://huggingface.co/sgugger). The original code can be found [here](https://github.com/laiguokun/Funnel-Transformer).
+
+## Usage tips
+
+- Since Funnel Transformer uses pooling, the sequence length of the hidden states changes after each block of layers. This way, their length is divided by 2, which speeds up the computation of the next hidden states.
+ The base model therefore has a final sequence length that is a quarter of the original one. This model can be used
+ directly for tasks that just require a sentence summary (like sequence classification or multiple choice). For other
+ tasks, the full model is used; this full model has a decoder that upsamples the final hidden states to the same
+ sequence length as the input.
+- For tasks such as classification, this is not a problem, but for tasks like masked language modeling or token classification, we need a hidden state with the same sequence length as the original input. In those cases, the final hidden states are upsampled to the input sequence length and go through two additional layers. That's why there are two versions of each checkpoint. The version suffixed with “-base” contains only the three blocks, while the version without that suffix contains the three blocks and the upsampling head with its additional layers.
+- The Funnel Transformer checkpoints are all available with a full version and a base version. The first ones should be
+ used for [`FunnelModel`], [`FunnelForPreTraining`],
+ [`FunnelForMaskedLM`], [`FunnelForTokenClassification`] and
+ [`FunnelForQuestionAnswering`]. The second ones should be used for
+ [`FunnelBaseModel`], [`FunnelForSequenceClassification`] and
+ [`FunnelForMultipleChoice`].
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+
+## FunnelConfig
+
+[[autodoc]] FunnelConfig
+
+## FunnelTokenizer
+
+[[autodoc]] FunnelTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## FunnelTokenizerFast
+
+[[autodoc]] FunnelTokenizerFast
+
+## Funnel specific outputs
+
+[[autodoc]] models.funnel.modeling_funnel.FunnelForPreTrainingOutput
+
+[[autodoc]] models.funnel.modeling_tf_funnel.TFFunnelForPreTrainingOutput
+
+
+
+
+## FunnelBaseModel
+
+[[autodoc]] FunnelBaseModel
+ - forward
+
+## FunnelModel
+
+[[autodoc]] FunnelModel
+ - forward
+
+## FunnelModelForPreTraining
+
+[[autodoc]] FunnelForPreTraining
+ - forward
+
+## FunnelForMaskedLM
+
+[[autodoc]] FunnelForMaskedLM
+ - forward
+
+## FunnelForSequenceClassification
+
+[[autodoc]] FunnelForSequenceClassification
+ - forward
+
+## FunnelForMultipleChoice
+
+[[autodoc]] FunnelForMultipleChoice
+ - forward
+
+## FunnelForTokenClassification
+
+[[autodoc]] FunnelForTokenClassification
+ - forward
+
+## FunnelForQuestionAnswering
+
+[[autodoc]] FunnelForQuestionAnswering
+ - forward
+
+
+
+
+## TFFunnelBaseModel
+
+[[autodoc]] TFFunnelBaseModel
+ - call
+
+## TFFunnelModel
+
+[[autodoc]] TFFunnelModel
+ - call
+
+## TFFunnelModelForPreTraining
+
+[[autodoc]] TFFunnelForPreTraining
+ - call
+
+## TFFunnelForMaskedLM
+
+[[autodoc]] TFFunnelForMaskedLM
+ - call
+
+## TFFunnelForSequenceClassification
+
+[[autodoc]] TFFunnelForSequenceClassification
+ - call
+
+## TFFunnelForMultipleChoice
+
+[[autodoc]] TFFunnelForMultipleChoice
+ - call
+
+## TFFunnelForTokenClassification
+
+[[autodoc]] TFFunnelForTokenClassification
+ - call
+
+## TFFunnelForQuestionAnswering
+
+[[autodoc]] TFFunnelForQuestionAnswering
+ - call
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/fuyu.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/fuyu.md
new file mode 100644
index 0000000000000000000000000000000000000000..bd55737da58ff8df3753cff4b9e27dfdcf7bf2a9
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/fuyu.md
@@ -0,0 +1,115 @@
+
+
+# Fuyu
+
+## Overview
+
+The Fuyu model was created by [ADEPT](https://www.adept.ai/blog/fuyu-8b), and authored by Rohan Bavishi, Erich Elsen, Curtis Hawthorne, Maxwell Nye, Augustus Odena, Arushi Somani, Sağnak Taşırlar.
+
+The authors introduced Fuyu-8B, a decoder-only multimodal model based on the classic transformers architecture, with query and key normalization. A linear encoder is added to create multimodal embeddings from image inputs.
+
+By treating image tokens like text tokens and using a special image-newline character, the model knows when an image line ends. Image positional embeddings are removed. This avoids the need for different training phases for various image resolutions. With 8 billion parameters and licensed under CC-BY-NC, Fuyu-8B is notable for its ability to handle both text and images, its impressive context size of 16K, and its overall performance.
+
+
+
+The `Fuyu` models were trained using `bfloat16`, but the original inference uses `float16` The checkpoints uploaded on the hub use `torch_dtype = 'float16'` which will be
+used by the `AutoModel` API to cast the checkpoints from `torch.float32` to `torch.float16`.
+
+The `dtype` of the online weights is mostly irrelevant, unless you are using `torch_dtype="auto"` when initializing a model using `model = AutoModelForCausalLM.from_pretrained("path", torch_dtype = "auto")`. The reason is that the model will first be downloaded ( using the `dtype` of the checkpoints online) then it will be cast to the default `dtype` of `torch` (becomes `torch.float32`). Users should specify the `torch_dtype` they want, and if they don't it will be `torch.float32`.
+
+Finetuning the model in `float16` is not recommended and known to produce `nan`, as such the model should be fine-tuned in `bfloat16`.
+
+
+
+
+Tips:
+
+- To convert the model, you need to clone the original repository using `git clone https://github.com/persimmon-ai-labs/adept-inference`, then get the checkpoints:
+
+```bash
+git clone https://github.com/persimmon-ai-labs/adept-inference
+wget path/to/fuyu-8b-model-weights.tar
+tar -xvf fuyu-8b-model-weights.tar
+python src/transformers/models/fuyu/convert_fuyu_weights_to_hf.py --input_dir /path/to/downloaded/fuyu/weights/ --output_dir /output/path \
+ --pt_model_path /path/to/fuyu_8b_release/iter_0001251/mp_rank_00/model_optim_rng.pt
+ --ada_lib_path /path/to/adept-inference
+```
+
+For the chat model:
+```bash
+wget https://axtkn4xl5cip.objectstorage.us-phoenix-1.oci.customer-oci.com/n/axtkn4xl5cip/b/adept-public-data/o/8b_chat_model_release.tar
+tar -xvf 8b_base_model_release.tar
+```
+Then, model can be loaded via:
+
+```py
+from transformers import FuyuConfig, FuyuForCausalLM
+model_config = FuyuConfig()
+model = FuyuForCausalLM(model_config).from_pretrained('/output/path')
+```
+
+Inputs need to be passed through a specific Processor to have the correct formats.
+A processor requires an image_processor and a tokenizer. Hence, inputs can be loaded via:
+
+```py
+from PIL import Image
+from transformers import AutoTokenizer
+from transformers.models.fuyu.processing_fuyu import FuyuProcessor
+from transformers.models.fuyu.image_processing_fuyu import FuyuImageProcessor
+
+
+tokenizer = AutoTokenizer.from_pretrained('adept-hf-collab/fuyu-8b')
+image_processor = FuyuImageProcessor()
+
+
+processor = FuyuProcessor(image_processor=image_processor, tokenizer=tokenizer)
+text_prompt = "Generate a coco-style caption.\\n"
+
+bus_image_url = "https://huggingface.co/datasets/hf-internal-testing/fixtures-captioning/resolve/main/bus.png"
+bus_image_pil = Image.open(io.BytesIO(requests.get(bus_image_url).content))
+inputs_to_model = processor(images=bus_image_pil, text=text_prompt)
+
+
+```
+
+This model was contributed by [Molbap](https://huggingface.co/Molbap).
+The original code can be found [here](https://github.com/persimmon-ai-labs/adept-inference).
+
+- Fuyu uses a `sentencepiece` based tokenizer, with a `Unigram` model. It supports bytefallback, which is only available in `tokenizers==0.14.0` for the fast tokenizer.
+The `LlamaTokenizer` is used as it is a standard wrapper around sentencepiece.
+
+- The authors suggest to use the following prompt for image captioning: `f"Generate a coco-style caption.\\n"`
+
+
+## FuyuConfig
+
+[[autodoc]] FuyuConfig
+
+## FuyuForCausalLM
+
+[[autodoc]] FuyuForCausalLM
+ - forward
+
+## FuyuImageProcessor
+
+[[autodoc]] FuyuImageProcessor
+ - __call__
+
+## FuyuProcessor
+
+[[autodoc]] FuyuProcessor
+ - __call__
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gemma.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gemma.md
new file mode 100644
index 0000000000000000000000000000000000000000..abd077af8da17098f285934f83142702d62b2be5
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gemma.md
@@ -0,0 +1,76 @@
+
+
+# Gemma
+
+## Overview
+
+The Gemma model was proposed in [Gemma: Open Models Based on Gemini Technology and Research](https://blog.google/technology/developers/gemma-open-models/) by Gemma Team, Google.
+Gemma models are trained on 6T tokens, and released with 2 versions, 2b and 7b.
+
+The abstract from the paper is the following:
+
+*This work introduces Gemma, a new family of open language models demonstrating strong performance across academic benchmarks for language understanding, reasoning, and safety. We release two sizes of models (2 billion and 7 billion parameters), and provide both pretrained and fine-tuned checkpoints. Gemma outperforms similarly sized open models on 11 out of 18 text-based tasks, and we present comprehensive evaluations of safety and responsibility aspects of the models, alongside a detailed description of our model development. We believe the responsible release of LLMs is critical for improving the safety of frontier models, and for enabling the next wave of LLM innovations*
+
+Tips:
+
+- The original checkpoints can be converted using the conversion script `src/transformers/models/gemma/convert_gemma_weights_to_hf.py`
+
+This model was contributed by [Arthur Zucker](https://huggingface.co/ArthurZ), [Younes Belkada](https://huggingface.co/ybelkada), [Sanchit Gandhi](https://huggingface.co/sanchit-gandhi), [Pedro Cuenca](https://huggingface.co/pcuenq).
+
+
+## GemmaConfig
+
+[[autodoc]] GemmaConfig
+
+## GemmaTokenizer
+
+[[autodoc]] GemmaTokenizer
+
+
+## GemmaTokenizerFast
+
+[[autodoc]] GemmaTokenizerFast
+
+## GemmaModel
+
+[[autodoc]] GemmaModel
+ - forward
+
+## GemmaForCausalLM
+
+[[autodoc]] GemmaForCausalLM
+ - forward
+
+## GemmaForSequenceClassification
+
+[[autodoc]] GemmaForSequenceClassification
+ - forward
+
+## GemmaForTokenClassification
+
+[[autodoc]] GemmaForTokenClassification
+ - forward
+
+## FlaxGemmaModel
+
+[[autodoc]] FlaxGemmaModel
+ - __call__
+
+## FlaxGemmaForCausalLM
+
+[[autodoc]] FlaxGemmaForCausalLM
+ - __call__
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gemma2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gemma2.md
new file mode 100644
index 0000000000000000000000000000000000000000..431c4ecd25f238de01abd8a71a9cde5a79be865e
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gemma2.md
@@ -0,0 +1,64 @@
+
+
+
+# Gemma2
+
+## Overview
+
+The Gemma2 model was proposed in [Gemma2: Open Models Based on Gemini Technology and Research](https://blog.google/technology/developers/google-gemma-2/) by Gemma2 Team, Google.
+Two Gemma2 models are released, with parameters sizes of 9 billion (9B) and 27 billion (27B).
+
+The abstract from the blog post is the following:
+
+*Now we’re officially releasing Gemma 2 to researchers and developers globally. Available in both 9 billion (9B) and 27 billion (27B) parameter sizes, Gemma 2 is higher-performing and more efficient at inference than the first generation, with significant safety advancements built in. In fact, at 27B, it offers competitive alternatives to models more than twice its size, delivering the kind of performance that was only possible with proprietary models as recently as December.*
+
+Tips:
+
+- The original checkpoints can be converted using the conversion script `src/transformers/models/Gemma2/convert_Gemma2_weights_to_hf.py`
+
+
+
+- Gemma2 uses sliding window attention every second layer, which makes it unsuitable for typical kv caching with [`~DynamicCache`] or tuples of tensors. To enable caching in Gemma2 forward call, you must initialize a [`~HybridCache`] instance and pass it as `past_key_values` to the forward call. Note, that you also have to prepare `cache_position` if the `past_key_values` already contains previous keys and values.
+
+
+
+This model was contributed by [Arthur Zucker](https://huggingface.co/ArthurZ), [Pedro Cuenca](https://huggingface.co/pcuenq) and [Tom Arsen]().
+
+
+## Gemma2Config
+
+[[autodoc]] Gemma2Config
+
+## Gemma2Model
+
+[[autodoc]] Gemma2Model
+ - forward
+
+## Gemma2ForCausalLM
+
+[[autodoc]] Gemma2ForCausalLM
+ - forward
+
+## Gemma2ForSequenceClassification
+
+[[autodoc]] Gemma2ForSequenceClassification
+ - forward
+
+## Gemma2ForTokenClassification
+
+[[autodoc]] Gemma2ForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/git.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/git.md
new file mode 100644
index 0000000000000000000000000000000000000000..bffa98b89e3b731467e464a68e836af45390d48e
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/git.md
@@ -0,0 +1,79 @@
+
+
+# GIT
+
+## Overview
+
+The GIT model was proposed in [GIT: A Generative Image-to-text Transformer for Vision and Language](https://arxiv.org/abs/2205.14100) by
+Jianfeng Wang, Zhengyuan Yang, Xiaowei Hu, Linjie Li, Kevin Lin, Zhe Gan, Zicheng Liu, Ce Liu, Lijuan Wang. GIT is a decoder-only Transformer
+that leverages [CLIP](clip)'s vision encoder to condition the model on vision inputs besides text. The model obtains state-of-the-art results on
+image captioning and visual question answering benchmarks.
+
+The abstract from the paper is the following:
+
+*In this paper, we design and train a Generative Image-to-text Transformer, GIT, to unify vision-language tasks such as image/video captioning and question answering. While generative models provide a consistent network architecture between pre-training and fine-tuning, existing work typically contains complex structures (uni/multi-modal encoder/decoder) and depends on external modules such as object detectors/taggers and optical character recognition (OCR). In GIT, we simplify the architecture as one image encoder and one text decoder under a single language modeling task. We also scale up the pre-training data and the model size to boost the model performance. Without bells and whistles, our GIT establishes new state of the arts on 12 challenging benchmarks with a large margin. For instance, our model surpasses the human performance for the first time on TextCaps (138.2 vs. 125.5 in CIDEr). Furthermore, we present a new scheme of generation-based image classification and scene text recognition, achieving decent performance on standard benchmarks.*
+
+
+
+ GIT architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/microsoft/GenerativeImage2Text).
+
+## Usage tips
+
+- GIT is implemented in a very similar way to GPT-2, the only difference being that the model is also conditioned on `pixel_values`.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with GIT.
+
+- Demo notebooks regarding inference + fine-tuning GIT on custom data can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/GIT).
+- See also: [Causal language modeling task guide](../tasks/language_modeling)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we will review it.
+The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## GitVisionConfig
+
+[[autodoc]] GitVisionConfig
+
+## GitVisionModel
+
+[[autodoc]] GitVisionModel
+ - forward
+
+## GitConfig
+
+[[autodoc]] GitConfig
+ - all
+
+## GitProcessor
+
+[[autodoc]] GitProcessor
+ - __call__
+
+## GitModel
+
+[[autodoc]] GitModel
+ - forward
+
+## GitForCausalLM
+
+[[autodoc]] GitForCausalLM
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/glm.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/glm.md
new file mode 100644
index 0000000000000000000000000000000000000000..be0b367b62ec0264373c756ca708f3bb22070973
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/glm.md
@@ -0,0 +1,99 @@
+
+
+# GLM
+
+## Overview
+
+The GLM Model was proposed
+in [ChatGLM: A Family of Large Language Models from GLM-130B to GLM-4 All Tools](https://arxiv.org/html/2406.12793v1)
+by GLM Team, THUDM & ZhipuAI.
+
+The abstract from the paper is the following:
+
+*We introduce ChatGLM, an evolving family of large language models that we have been developing over time. This report
+primarily focuses on the GLM-4 language series, which includes GLM-4, GLM-4-Air, and GLM-4-9B. They represent our most
+capable models that are trained with all the insights and lessons gained from the preceding three generations of
+ChatGLM. To date, the GLM-4 models are pre-trained on ten trillions of tokens mostly in Chinese and English, along with
+a small set of corpus from 24 languages, and aligned primarily for Chinese and English usage. The high-quality alignment
+is achieved via a multi-stage post-training process, which involves supervised fine-tuning and learning from human
+feedback. Evaluations show that GLM-4 1) closely rivals or outperforms GPT-4 in terms of general metrics such as MMLU,
+GSM8K, MATH, BBH, GPQA, and HumanEval, 2) gets close to GPT-4-Turbo in instruction following as measured by IFEval, 3)
+matches GPT-4 Turbo (128K) and Claude 3 for long context tasks, and 4) outperforms GPT-4 in Chinese alignments as
+measured by AlignBench. The GLM-4 All Tools model is further aligned to understand user intent and autonomously decide
+when and which tool(s) to use—including web browser, Python interpreter, text-to-image model, and user-defined
+functions—to effectively complete complex tasks. In practical applications, it matches and even surpasses GPT-4 All
+Tools in tasks like accessing online information via web browsing and solving math problems using Python interpreter.
+Over the course, we have open-sourced a series of models, including ChatGLM-6B (three generations), GLM-4-9B (128K, 1M),
+GLM-4V-9B, WebGLM, and CodeGeeX, attracting over 10 million downloads on Hugging face in the year 2023 alone.*
+
+Tips:
+
+- This model was contributed by [THUDM](https://huggingface.co/THUDM). The most recent code can be
+ found [here](https://github.com/thudm/GLM-4).
+
+
+## Usage tips
+
+`GLM-4` can be found on the [Huggingface Hub](https://huggingface.co/collections/THUDM/glm-4-665fcf188c414b03c2f7e3b7)
+
+In the following, we demonstrate how to use `glm-4-9b-chat` for the inference. Note that we have used the ChatML format for dialog, in this demo we show how to leverage `apply_chat_template` for this purpose.
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+>>> device = "cuda" # the device to load the model onto
+
+>>> model = AutoModelForCausalLM.from_pretrained("THUDM/glm-4-9b-chat", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("THUDM/glm-4-9b-chat")
+
+>>> prompt = "Give me a short introduction to large language model."
+
+>>> messages = [{"role": "user", "content": prompt}]
+
+>>> text = tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
+
+>>> model_inputs = tokenizer([text], return_tensors="pt").to(device)
+
+>>> generated_ids = model.generate(model_inputs.input_ids, max_new_tokens=512, do_sample=True)
+
+>>> generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(model_inputs.input_ids, generated_ids)]
+
+>>> response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+```
+
+## GlmConfig
+
+[[autodoc]] GlmConfig
+
+## GlmModel
+
+[[autodoc]] GlmModel
+ - forward
+
+## GlmForCausalLM
+
+[[autodoc]] GlmForCausalLM
+ - forward
+
+## GlmForSequenceClassification
+
+[[autodoc]] GlmForSequenceClassification
+ - forward
+
+## GlmForTokenClassification
+
+[[autodoc]] GlmForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/glpn.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/glpn.md
new file mode 100644
index 0000000000000000000000000000000000000000..b57d1a7ccdda7f3814a401e832ebc0a13bfdfd49
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/glpn.md
@@ -0,0 +1,72 @@
+
+
+# GLPN
+
+
+
+This is a recently introduced model so the API hasn't been tested extensively. There may be some bugs or slight
+breaking changes to fix it in the future. If you see something strange, file a [Github Issue](https://github.com/huggingface/transformers/issues/new?assignees=&labels=&template=bug-report.md&title).
+
+
+
+## Overview
+
+The GLPN model was proposed in [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://arxiv.org/abs/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
+GLPN combines [SegFormer](segformer)'s hierarchical mix-Transformer with a lightweight decoder for monocular depth estimation. The proposed decoder shows better performance than the previously proposed decoders, with considerably
+less computational complexity.
+
+The abstract from the paper is the following:
+
+*Depth estimation from a single image is an important task that can be applied to various fields in computer vision, and has grown rapidly with the development of convolutional neural networks. In this paper, we propose a novel structure and training strategy for monocular depth estimation to further improve the prediction accuracy of the network. We deploy a hierarchical transformer encoder to capture and convey the global context, and design a lightweight yet powerful decoder to generate an estimated depth map while considering local connectivity. By constructing connected paths between multi-scale local features and the global decoding stream with our proposed selective feature fusion module, the network can integrate both representations and recover fine details. In addition, the proposed decoder shows better performance than the previously proposed decoders, with considerably less computational complexity. Furthermore, we improve the depth-specific augmentation method by utilizing an important observation in depth estimation to enhance the model. Our network achieves state-of-the-art performance over the challenging depth dataset NYU Depth V2. Extensive experiments have been conducted to validate and show the effectiveness of the proposed approach. Finally, our model shows better generalisation ability and robustness than other comparative models.*
+
+
+
+ Summary of the approach. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found [here](https://github.com/vinvino02/GLPDepth).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with GLPN.
+
+- Demo notebooks for [`GLPNForDepthEstimation`] can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/GLPN).
+- [Monocular depth estimation task guide](../tasks/monocular_depth_estimation)
+
+## GLPNConfig
+
+[[autodoc]] GLPNConfig
+
+## GLPNFeatureExtractor
+
+[[autodoc]] GLPNFeatureExtractor
+ - __call__
+
+## GLPNImageProcessor
+
+[[autodoc]] GLPNImageProcessor
+ - preprocess
+
+## GLPNModel
+
+[[autodoc]] GLPNModel
+ - forward
+
+## GLPNForDepthEstimation
+
+[[autodoc]] GLPNForDepthEstimation
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt-sw3.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt-sw3.md
new file mode 100644
index 0000000000000000000000000000000000000000..f69bd958e9c5f1f7ae0e8234215d57fa6002dd80
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt-sw3.md
@@ -0,0 +1,69 @@
+
+
+# GPT-Sw3
+
+## Overview
+
+The GPT-Sw3 model was first proposed in
+[Lessons Learned from GPT-SW3: Building the First Large-Scale Generative Language Model for Swedish](http://www.lrec-conf.org/proceedings/lrec2022/pdf/2022.lrec-1.376.pdf)
+by Ariel Ekgren, Amaru Cuba Gyllensten, Evangelia Gogoulou, Alice Heiman, Severine Verlinden, Joey Öhman,
+Fredrik Carlsson, Magnus Sahlgren.
+
+Since that first paper the authors have extended their work and trained new models on their new 1.2TB corpora named The Nordic Pile.
+
+GPT-Sw3 is a collection of large decoder-only pretrained transformer language models that were developed by AI Sweden
+in collaboration with RISE and the WASP WARA for Media and Language. GPT-Sw3 has been trained on a dataset containing
+320B tokens in Swedish, Norwegian, Danish, Icelandic, English, and programming code. The model was pretrained using a
+causal language modeling (CLM) objective utilizing the NeMo Megatron GPT implementation.
+
+This model was contributed by [AI Sweden Models](https://huggingface.co/AI-Sweden-Models).
+
+## Usage example
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForCausalLM
+
+>>> tokenizer = AutoTokenizer.from_pretrained("AI-Sweden-Models/gpt-sw3-356m")
+>>> model = AutoModelForCausalLM.from_pretrained("AI-Sweden-Models/gpt-sw3-356m")
+
+>>> input_ids = tokenizer("Träd är fina för att", return_tensors="pt")["input_ids"]
+
+>>> generated_token_ids = model.generate(inputs=input_ids, max_new_tokens=10, do_sample=True)[0]
+
+>>> print(tokenizer.decode(generated_token_ids))
+Träd är fina för att de är färgstarka. Men ibland är det fint
+```
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+
+
+The implementation uses the `GPT2Model` coupled with our `GPTSw3Tokenizer`. Refer to [GPT2Model documentation](gpt2)
+for API reference and examples.
+
+Note that sentencepiece is required to use our tokenizer and can be installed with `pip install transformers[sentencepiece]` or `pip install sentencepiece`
+
+
+
+## GPTSw3Tokenizer
+
+[[autodoc]] GPTSw3Tokenizer
+ - save_vocabulary
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt2.md
new file mode 100644
index 0000000000000000000000000000000000000000..89a0429cca411061f47f94d23cea71bc64977410
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt2.md
@@ -0,0 +1,306 @@
+
+
+# OpenAI GPT2
+
+
+
+## Overview
+
+OpenAI GPT-2 model was proposed in [Language Models are Unsupervised Multitask Learners](https://cdn.openai.com/better-language-models/language_models_are_unsupervised_multitask_learners.pdf) by Alec
+Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever from [OpenAI](https://huggingface.co/openai). It's a causal (unidirectional)
+transformer pretrained using language modeling on a very large corpus of ~40 GB of text data.
+
+The abstract from the paper is the following:
+
+*GPT-2 is a large transformer-based language model with 1.5 billion parameters, trained on a dataset[1] of 8 million
+web pages. GPT-2 is trained with a simple objective: predict the next word, given all of the previous words within some
+text. The diversity of the dataset causes this simple goal to contain naturally occurring demonstrations of many tasks
+across diverse domains. GPT-2 is a direct scale-up of GPT, with more than 10X the parameters and trained on more than
+10X the amount of data.*
+
+[Write With Transformer](https://transformer.huggingface.co/doc/gpt2-large) is a webapp created and hosted by
+Hugging Face showcasing the generative capabilities of several models. GPT-2 is one of them and is available in five
+different sizes: small, medium, large, xl and a distilled version of the small checkpoint: *distilgpt-2*.
+
+This model was contributed by [thomwolf](https://huggingface.co/thomwolf). The original code can be found [here](https://openai.com/blog/better-language-models/).
+
+## Usage tips
+
+- GPT-2 is a model with absolute position embeddings so it's usually advised to pad the inputs on the right rather than
+ the left.
+- GPT-2 was trained with a causal language modeling (CLM) objective and is therefore powerful at predicting the next
+ token in a sequence. Leveraging this feature allows GPT-2 to generate syntactically coherent text as it can be
+ observed in the *run_generation.py* example script.
+- The model can take the *past_key_values* (for PyTorch) or *past* (for TF) as input, which is the previously computed
+ key/value attention pairs. Using this (*past_key_values* or *past*) value prevents the model from re-computing
+ pre-computed values in the context of text generation. For PyTorch, see *past_key_values* argument of the
+ [`GPT2Model.forward`] method, or for TF the *past* argument of the
+ [`TFGPT2Model.call`] method for more information on its usage.
+- Enabling the *scale_attn_by_inverse_layer_idx* and *reorder_and_upcast_attn* flags will apply the training stability
+ improvements from [Mistral](https://github.com/stanford-crfm/mistral/) (for PyTorch only).
+
+## Usage example
+
+The `generate()` method can be used to generate text using GPT2 model.
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("gpt2")
+>>> tokenizer = AutoTokenizer.from_pretrained("gpt2")
+
+>>> prompt = "GPT2 is a model developed by OpenAI."
+
+>>> input_ids = tokenizer(prompt, return_tensors="pt").input_ids
+
+>>> gen_tokens = model.generate(
+... input_ids,
+... do_sample=True,
+... temperature=0.9,
+... max_length=100,
+... )
+>>> gen_text = tokenizer.batch_decode(gen_tokens)[0]
+```
+
+## Using Flash Attention 2
+
+Flash Attention 2 is a faster, optimized version of the attention scores computation which relies on `cuda` kernels.
+
+### Installation
+
+First, check whether your hardware is compatible with Flash Attention 2. The latest list of compatible hardware can be found in the [official documentation](https://github.com/Dao-AILab/flash-attention#installation-and-features). If your hardware is not compatible with Flash Attention 2, you can still benefit from attention kernel optimisations through Better Transformer support covered [above](https://huggingface.co/docs/transformers/main/en/model_doc/bark#using-better-transformer).
+
+Next, [install](https://github.com/Dao-AILab/flash-attention#installation-and-features) the latest version of Flash Attention 2:
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+### Usage
+
+To load a model using Flash Attention 2, we can pass the argument `attn_implementation="flash_attention_2"` to [`.from_pretrained`](https://huggingface.co/docs/transformers/main/en/main_classes/model#transformers.PreTrainedModel.from_pretrained). We'll also load the model in half-precision (e.g. `torch.float16`), since it results in almost no degradation to audio quality but significantly lower memory usage and faster inference:
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+>>> device = "cuda" # the device to load the model onto
+
+>>> model = AutoModelForCausalLM.from_pretrained("gpt2", torch_dtype=torch.float16, attn_implementation="flash_attention_2")
+>>> tokenizer = AutoTokenizer.from_pretrained("gpt2")
+
+>>> prompt = "def hello_world():"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to(device)
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+```
+
+
+### Expected speedups
+
+Below is an expected speedup diagram that compares pure inference time between the native implementation in transformers using `gpt2` checkpoint and the Flash Attention 2 version of the model using a sequence length of 512.
+
+
+
+
+
+
+## Using Scaled Dot Product Attention (SDPA)
+PyTorch includes a native scaled dot-product attention (SDPA) operator as part of `torch.nn.functional`. This function
+encompasses several implementations that can be applied depending on the inputs and the hardware in use. See the
+[official documentation](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)
+or the [GPU Inference](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)
+page for more information.
+
+SDPA is used by default for `torch>=2.1.1` when an implementation is available, but you may also set
+`attn_implementation="sdpa"` in `from_pretrained()` to explicitly request SDPA to be used.
+
+```python
+from transformers import AutoModelForCausalLM
+model = AutoModelForCausalLM.from_pretrained("gpt2", torch_dtype=torch.float16, attn_implementation="sdpa")
+...
+```
+
+For the best speedups, we recommend loading the model in half-precision (e.g. `torch.float16` or `torch.bfloat16`).
+
+On a local benchmark (rtx3080ti-16GB, PyTorch 2.2.1, OS Ubuntu 22.04) using `float16` with
+[gpt2-large](https://huggingface.co/openai-community/gpt2-large), we saw the
+following speedups during training and inference.
+
+### Training
+| Batch size | Seq len | Time per batch (Eager - s) | Time per batch (SDPA - s) | Speedup (%) | Eager peak mem (MB) | SDPA peak mem (MB) | Mem saving (%) |
+|-----------:|--------:|----------------------------:|--------------------------:|------------:|--------------------:|-------------------:|------------------:|
+| 1 | 128 | 0.039 | 0.032 | 23.042 | 3482.32 | 3494.62 | -0.352 |
+| 1 | 256 | 0.073 | 0.059 | 25.15 | 3546.66 | 3552.6 | -0.167 |
+| 1 | 512 | 0.155 | 0.118 | 30.96 | 4230.1 | 3665.59 | 15.4 |
+| 1 | 1024 | 0.316 | 0.209 | 50.839 | 8682.26 | 4881.09 | 77.875 |
+| 2 | 128 | 0.07 | 0.06 | 15.324 | 3557.8 | 3545.91 | 0.335 |
+| 2 | 256 | 0.143 | 0.122 | 16.53 | 3901.5 | 3657.68 | 6.666 |
+| 2 | 512 | 0.267 | 0.213 | 25.626 | 7062.21 | 4876.47 | 44.822 |
+| 2 | 1024 | OOM | 0.404 | / | OOM | 8096.35 | SDPA does not OOM |
+| 4 | 128 | 0.134 | 0.128 | 4.412 | 3675.79 | 3648.72 | 0.742 |
+| 4 | 256 | 0.243 | 0.217 | 12.292 | 6129.76 | 4871.12 | 25.839 |
+| 4 | 512 | 0.494 | 0.406 | 21.687 | 12466.6 | 8102.64 | 53.858 |
+| 4 | 1024 | OOM | 0.795 | / | OOM | 14568.2 | SDPA does not OOM |
+
+### Inference
+| Batch size | Seq len | Per token latency Eager (ms) | Per token latency SDPA (ms) | Speedup (%) | Mem Eager (MB) | Mem SDPA (MB) | Mem saved (%) |
+|-----------:|--------:|-----------------------------:|----------------------------:|------------:|---------------:|--------------:|--------------:|
+| 1 | 128 | 7.991 | 6.968 | 14.681 | 1685.2 | 1701.32 | -0.947 |
+| 1 | 256 | 8.462 | 7.199 | 17.536 | 1745.49 | 1770.78 | -1.428 |
+| 1 | 512 | 8.68 | 7.853 | 10.529 | 1907.69 | 1921.29 | -0.708 |
+| 1 | 768 | 9.101 | 8.365 | 8.791 | 2032.93 | 2068.12 | -1.701 |
+| 2 | 128 | 9.169 | 9.001 | 1.861 | 1803.84 | 1811.4 | -0.418 |
+| 2 | 256 | 9.907 | 9.78 | 1.294 | 1907.72 | 1921.44 | -0.714 |
+| 2 | 512 | 11.519 | 11.644 | -1.071 | 2176.86 | 2197.75 | -0.951 |
+| 2 | 768 | 13.022 | 13.407 | -2.873 | 2464.3 | 2491.06 | -1.074 |
+| 4 | 128 | 10.097 | 9.831 | 2.709 | 1942.25 | 1985.13 | -2.16 |
+| 4 | 256 | 11.599 | 11.398 | 1.764 | 2177.28 | 2197.86 | -0.937 |
+| 4 | 512 | 14.653 | 14.45 | 1.411 | 2753.16 | 2772.57 | -0.7 |
+| 4 | 768 | 17.846 | 17.617 | 1.299 | 3327.04 | 3343.97 | -0.506 |
+
+
+
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with GPT2. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- A blog on how to [Finetune a non-English GPT-2 Model with Hugging Face](https://www.philschmid.de/fine-tune-a-non-english-gpt-2-model-with-huggingface).
+- A blog on [How to generate text: using different decoding methods for language generation with Transformers](https://huggingface.co/blog/how-to-generate) with GPT-2.
+- A blog on [Training CodeParrot 🦜 from Scratch](https://huggingface.co/blog/codeparrot), a large GPT-2 model.
+- A blog on [Faster Text Generation with TensorFlow and XLA](https://huggingface.co/blog/tf-xla-generate) with GPT-2.
+- A blog on [How to train a Language Model with Megatron-LM](https://huggingface.co/blog/megatron-training) with a GPT-2 model.
+- A notebook on how to [finetune GPT2 to generate lyrics in the style of your favorite artist](https://colab.research.google.com/github/AlekseyKorshuk/huggingartists/blob/master/huggingartists-demo.ipynb). 🌎
+- A notebook on how to [finetune GPT2 to generate tweets in the style of your favorite Twitter user](https://colab.research.google.com/github/borisdayma/huggingtweets/blob/master/huggingtweets-demo.ipynb). 🌎
+- [Causal language modeling](https://huggingface.co/course/en/chapter7/6?fw=pt#training-a-causal-language-model-from-scratch) chapter of the 🤗 Hugging Face Course.
+- [`GPT2LMHeadModel`] is supported by this [causal language modeling example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/language-modeling#gpt-2gpt-and-causal-language-modeling), [text generation example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-generation), and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb).
+- [`TFGPT2LMHeadModel`] is supported by this [causal language modeling example script](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/language-modeling#run_clmpy) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb).
+- [`FlaxGPT2LMHeadModel`] is supported by this [causal language modeling example script](https://github.com/huggingface/transformers/tree/main/examples/flax/language-modeling#causal-language-modeling) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/causal_language_modeling_flax.ipynb).
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## GPT2Config
+
+[[autodoc]] GPT2Config
+
+## GPT2Tokenizer
+
+[[autodoc]] GPT2Tokenizer
+ - save_vocabulary
+
+## GPT2TokenizerFast
+
+[[autodoc]] GPT2TokenizerFast
+
+## GPT2 specific outputs
+
+[[autodoc]] models.gpt2.modeling_gpt2.GPT2DoubleHeadsModelOutput
+
+[[autodoc]] models.gpt2.modeling_tf_gpt2.TFGPT2DoubleHeadsModelOutput
+
+
+
+
+## GPT2Model
+
+[[autodoc]] GPT2Model
+ - forward
+
+## GPT2LMHeadModel
+
+[[autodoc]] GPT2LMHeadModel
+ - forward
+
+## GPT2DoubleHeadsModel
+
+[[autodoc]] GPT2DoubleHeadsModel
+ - forward
+
+## GPT2ForQuestionAnswering
+
+[[autodoc]] GPT2ForQuestionAnswering
+ - forward
+
+## GPT2ForSequenceClassification
+
+[[autodoc]] GPT2ForSequenceClassification
+ - forward
+
+## GPT2ForTokenClassification
+
+[[autodoc]] GPT2ForTokenClassification
+ - forward
+
+
+
+
+## TFGPT2Model
+
+[[autodoc]] TFGPT2Model
+ - call
+
+## TFGPT2LMHeadModel
+
+[[autodoc]] TFGPT2LMHeadModel
+ - call
+
+## TFGPT2DoubleHeadsModel
+
+[[autodoc]] TFGPT2DoubleHeadsModel
+ - call
+
+## TFGPT2ForSequenceClassification
+
+[[autodoc]] TFGPT2ForSequenceClassification
+ - call
+
+## TFSequenceClassifierOutputWithPast
+
+[[autodoc]] modeling_tf_outputs.TFSequenceClassifierOutputWithPast
+
+## TFGPT2Tokenizer
+
+[[autodoc]] TFGPT2Tokenizer
+
+
+
+
+## FlaxGPT2Model
+
+[[autodoc]] FlaxGPT2Model
+ - __call__
+
+## FlaxGPT2LMHeadModel
+
+[[autodoc]] FlaxGPT2LMHeadModel
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt_bigcode.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt_bigcode.md
new file mode 100644
index 0000000000000000000000000000000000000000..1635a9f50dd08e7f6c39a527ee46a6a59c44e9e8
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt_bigcode.md
@@ -0,0 +1,106 @@
+
+
+# GPTBigCode
+
+## Overview
+
+The GPTBigCode model was proposed in [SantaCoder: don't reach for the stars!](https://arxiv.org/abs/2301.03988) by BigCode. The listed authors are: Loubna Ben Allal, Raymond Li, Denis Kocetkov, Chenghao Mou, Christopher Akiki, Carlos Munoz Ferrandis, Niklas Muennighoff, Mayank Mishra, Alex Gu, Manan Dey, Logesh Kumar Umapathi, Carolyn Jane Anderson, Yangtian Zi, Joel Lamy Poirier, Hailey Schoelkopf, Sergey Troshin, Dmitry Abulkhanov, Manuel Romero, Michael Lappert, Francesco De Toni, Bernardo García del Río, Qian Liu, Shamik Bose, Urvashi Bhattacharyya, Terry Yue Zhuo, Ian Yu, Paulo Villegas, Marco Zocca, Sourab Mangrulkar, David Lansky, Huu Nguyen, Danish Contractor, Luis Villa, Jia Li, Dzmitry Bahdanau, Yacine Jernite, Sean Hughes, Daniel Fried, Arjun Guha, Harm de Vries, Leandro von Werra.
+
+The abstract from the paper is the following:
+
+*The BigCode project is an open-scientific collaboration working on the responsible development of large language models for code. This tech report describes the progress of the collaboration until December 2022, outlining the current state of the Personally Identifiable Information (PII) redaction pipeline, the experiments conducted to de-risk the model architecture, and the experiments investigating better preprocessing methods for the training data. We train 1.1B parameter models on the Java, JavaScript, and Python subsets of The Stack and evaluate them on the MultiPL-E text-to-code benchmark. We find that more aggressive filtering of near-duplicates can further boost performance and, surprisingly, that selecting files from repositories with 5+ GitHub stars deteriorates performance significantly. Our best model outperforms previous open-source multilingual code generation models (InCoder-6.7B and CodeGen-Multi-2.7B) in both left-to-right generation and infilling on the Java, JavaScript, and Python portions of MultiPL-E, despite being a substantially smaller model. All models are released under an OpenRAIL license at [this https URL.](https://huggingface.co/bigcode)*
+
+The model is an optimized [GPT2 model](https://huggingface.co/docs/transformers/model_doc/gpt2) with support for Multi-Query Attention.
+
+## Implementation details
+
+The main differences compared to GPT2.
+- Added support for Multi-Query Attention.
+- Use `gelu_pytorch_tanh` instead of classic `gelu`.
+- Avoid unnecessary synchronizations (this has since been added to GPT2 in #20061, but wasn't in the reference codebase).
+- Use Linear layers instead of Conv1D (good speedup but makes the checkpoints incompatible).
+- Merge `_attn` and `_upcast_and_reordered_attn`. Always merge the matmul with scaling. Rename `reorder_and_upcast_attn`->`attention_softmax_in_fp32`
+- Cache the attention mask value to avoid recreating it every time.
+- Use jit to fuse the attention fp32 casting, masking, softmax, and scaling.
+- Combine the attention and causal masks into a single one, pre-computed for the whole model instead of every layer.
+- Merge the key and value caches into one (this changes the format of layer_past/ present, does it risk creating problems?)
+- Use the memory layout (self.num_heads, 3, self.head_dim) instead of `(3, self.num_heads, self.head_dim)` for the QKV tensor with MHA. (prevents an overhead with the merged key and values, but makes the checkpoints incompatible with the original openai-community/gpt2 model).
+
+You can read more about the optimizations in the [original pull request](https://github.com/huggingface/transformers/pull/22575)
+
+## Combining Starcoder and Flash Attention 2
+
+First, make sure to install the latest version of Flash Attention 2 to include the sliding window attention feature.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Make also sure that you have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of flash-attn repository. Make also sure to load your model in half-precision (e.g. `torch.float16``)
+
+To load and run a model using Flash Attention 2, refer to the snippet below:
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+>>> device = "cuda" # the device to load the model onto
+
+>>> model = AutoModelForCausalLM.from_pretrained("bigcode/gpt_bigcode-santacoder", torch_dtype=torch.float16, attn_implementation="flash_attention_2")
+>>> tokenizer = AutoTokenizer.from_pretrained("bigcode/gpt_bigcode-santacoder")
+
+>>> prompt = "def hello_world():"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to(device)
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=30, do_sample=False)
+>>> tokenizer.batch_decode(generated_ids)[0]
+'def hello_world():\n print("hello world")\n\nif __name__ == "__main__":\n print("hello world")\n<|endoftext|>'
+```
+
+### Expected speedups
+
+Below is a expected speedup diagram that compares pure inference time between the native implementation in transformers using `bigcode/starcoder` checkpoint and the Flash Attention 2 version of the model using two different sequence lengths.
+
+
+
+
+
+
+## GPTBigCodeConfig
+
+[[autodoc]] GPTBigCodeConfig
+
+## GPTBigCodeModel
+
+[[autodoc]] GPTBigCodeModel
+ - forward
+
+## GPTBigCodeForCausalLM
+
+[[autodoc]] GPTBigCodeForCausalLM
+ - forward
+
+## GPTBigCodeForSequenceClassification
+
+[[autodoc]] GPTBigCodeForSequenceClassification
+ - forward
+
+## GPTBigCodeForTokenClassification
+
+[[autodoc]] GPTBigCodeForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt_neo.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt_neo.md
new file mode 100644
index 0000000000000000000000000000000000000000..3c7858c998207e9f7f52a177e4c57bdb114cce95
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt_neo.md
@@ -0,0 +1,147 @@
+
+
+# GPT Neo
+
+## Overview
+
+The GPTNeo model was released in the [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) repository by Sid
+Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy. It is a GPT2 like causal language model trained on the
+[Pile](https://pile.eleuther.ai/) dataset.
+
+The architecture is similar to GPT2 except that GPT Neo uses local attention in every other layer with a window size of
+256 tokens.
+
+This model was contributed by [valhalla](https://huggingface.co/valhalla).
+
+## Usage example
+
+The `generate()` method can be used to generate text using GPT Neo model.
+
+```python
+>>> from transformers import GPTNeoForCausalLM, GPT2Tokenizer
+
+>>> model = GPTNeoForCausalLM.from_pretrained("EleutherAI/gpt-neo-1.3B")
+>>> tokenizer = GPT2Tokenizer.from_pretrained("EleutherAI/gpt-neo-1.3B")
+
+>>> prompt = (
+... "In a shocking finding, scientists discovered a herd of unicorns living in a remote, "
+... "previously unexplored valley, in the Andes Mountains. Even more surprising to the "
+... "researchers was the fact that the unicorns spoke perfect English."
+... )
+
+>>> input_ids = tokenizer(prompt, return_tensors="pt").input_ids
+
+>>> gen_tokens = model.generate(
+... input_ids,
+... do_sample=True,
+... temperature=0.9,
+... max_length=100,
+... )
+>>> gen_text = tokenizer.batch_decode(gen_tokens)[0]
+```
+
+## Combining GPT-Neo and Flash Attention 2
+
+First, make sure to install the latest version of Flash Attention 2 to include the sliding window attention feature, and make sure your hardware is compatible with Flash-Attention 2. More details are available [here](https://huggingface.co/docs/transformers/perf_infer_gpu_one#flashattention-2) concerning the installation.
+
+Make sure as well to load your model in half-precision (e.g. `torch.float16`).
+
+To load and run a model using Flash Attention 2, refer to the snippet below:
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+>>> device = "cuda" # the device to load the model onto
+
+>>> model = AutoModelForCausalLM.from_pretrained("EleutherAI/gpt-neo-2.7B", torch_dtype=torch.float16, attn_implementation="flash_attention_2")
+>>> tokenizer = AutoTokenizer.from_pretrained("EleutherAI/gpt-neo-2.7B")
+
+>>> prompt = "def hello_world():"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to(device)
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"def hello_world():\n >>> run_script("hello.py")\n >>> exit(0)\n<|endoftext|>"
+```
+
+### Expected speedups
+
+Below is an expected speedup diagram that compares pure inference time between the native implementation in transformers using `EleutherAI/gpt-neo-2.7B` checkpoint and the Flash Attention 2 version of the model.
+Note that for GPT-Neo it is not possible to train / run on very long context as the max [position embeddings](https://huggingface.co/EleutherAI/gpt-neo-2.7B/blob/main/config.json#L58 ) is limited to 2048 - but this is applicable to all gpt-neo models and not specific to FA-2
+
+
+
+
+
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## GPTNeoConfig
+
+[[autodoc]] GPTNeoConfig
+
+
+
+
+
+## GPTNeoModel
+
+[[autodoc]] GPTNeoModel
+ - forward
+
+## GPTNeoForCausalLM
+
+[[autodoc]] GPTNeoForCausalLM
+ - forward
+
+## GPTNeoForQuestionAnswering
+
+[[autodoc]] GPTNeoForQuestionAnswering
+ - forward
+
+## GPTNeoForSequenceClassification
+
+[[autodoc]] GPTNeoForSequenceClassification
+ - forward
+
+## GPTNeoForTokenClassification
+
+[[autodoc]] GPTNeoForTokenClassification
+ - forward
+
+
+
+
+## FlaxGPTNeoModel
+
+[[autodoc]] FlaxGPTNeoModel
+ - __call__
+
+## FlaxGPTNeoForCausalLM
+
+[[autodoc]] FlaxGPTNeoForCausalLM
+ - __call__
+
+
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt_neox.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt_neox.md
new file mode 100644
index 0000000000000000000000000000000000000000..1319f2e93c141ddf6b75ec4aee732b6d58724cb3
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt_neox.md
@@ -0,0 +1,195 @@
+
+
+# GPT-NeoX
+
+## Overview
+
+We introduce GPT-NeoX-20B, a 20 billion parameter autoregressive language model trained on the Pile, whose weights will
+be made freely and openly available to the public through a permissive license. It is, to the best of our knowledge,
+the largest dense autoregressive model that has publicly available weights at the time of submission. In this work,
+we describe GPT-NeoX-20B's architecture and training and evaluate its performance on a range of language-understanding,
+mathematics, and knowledge-based tasks. We find that GPT-NeoX-20B is a particularly powerful few-shot reasoner and
+gains far more in performance when evaluated five-shot than similarly sized GPT-3 and FairSeq models. We open-source
+the training and evaluation code, as well as the model weights, at [https://github.com/EleutherAI/gpt-neox](https://github.com/EleutherAI/gpt-neox).
+
+Development of the model was led by Sid Black, Stella Biderman and Eric Hallahan, and the model was trained with
+generous the support of [CoreWeave](https://www.coreweave.com/).
+
+GPT-NeoX-20B was trained with fp16, thus it is recommended to initialize the model as follows:
+
+```python
+model = GPTNeoXForCausalLM.from_pretrained("EleutherAI/gpt-neox-20b").half().cuda()
+```
+
+GPT-NeoX-20B also has a different tokenizer from the one used in GPT-J-6B and GPT-Neo. The new tokenizer allocates
+additional tokens to whitespace characters, making the model more suitable for certain tasks like code generation.
+
+## Usage example
+
+The `generate()` method can be used to generate text using GPT Neo model.
+
+```python
+>>> from transformers import GPTNeoXForCausalLM, GPTNeoXTokenizerFast
+
+>>> model = GPTNeoXForCausalLM.from_pretrained("EleutherAI/gpt-neox-20b")
+>>> tokenizer = GPTNeoXTokenizerFast.from_pretrained("EleutherAI/gpt-neox-20b")
+
+>>> prompt = "GPTNeoX20B is a 20B-parameter autoregressive Transformer model developed by EleutherAI."
+
+>>> input_ids = tokenizer(prompt, return_tensors="pt").input_ids
+
+>>> gen_tokens = model.generate(
+... input_ids,
+... do_sample=True,
+... temperature=0.9,
+... max_length=100,
+... )
+>>> gen_text = tokenizer.batch_decode(gen_tokens)[0]
+```
+
+## Using Flash Attention 2
+
+Flash Attention 2 is an faster, optimized version of the model.
+
+### Installation
+
+First, check whether your hardware is compatible with Flash Attention 2. The latest list of compatible hardware can be found in the [official documentation](https://github.com/Dao-AILab/flash-attention#installation-and-features). If your hardware is not compatible with Flash Attention 2, you can still benefit from attention kernel optimisations through Better Transformer support covered [above](https://huggingface.co/docs/transformers/main/en/model_doc/bark#using-better-transformer).
+
+Next, [install](https://github.com/Dao-AILab/flash-attention#installation-and-features) the latest version of Flash Attention 2:
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+### Usage
+
+To load a model using Flash Attention 2, we can pass the argument `attn_implementation="flash_attention_2"` to [`.from_pretrained`](https://huggingface.co/docs/transformers/main/en/main_classes/model#transformers.PreTrainedModel.from_pretrained). We'll also load the model in half-precision (e.g. `torch.float16`), since it results in almost no degradation to audio quality but significantly lower memory usage and faster inference:
+
+```python
+>>> from transformers import GPTNeoXForCausalLM, GPTNeoXTokenizerFast
+
+model = GPTNeoXForCausalLM.from_pretrained("EleutherAI/gpt-neox-20b", torch_dtype=torch.float16, attn_implementation="flash_attention_2").to(device)
+...
+```
+
+
+### Expected speedups
+
+Below is an expected speedup diagram that compares pure inference time between the native implementation in transformers using `stockmark/gpt-neox-japanese-1.4b` checkpoint and the Flash Attention 2 version of the model using a sequence length of 2048.
+
+
+
+
+
+
+## Using Scaled Dot Product Attention (SDPA)
+PyTorch includes a native scaled dot-product attention (SDPA) operator as part of `torch.nn.functional`. This function
+encompasses several implementations that can be applied depending on the inputs and the hardware in use. See the
+[official documentation](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)
+or the [GPU Inference](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)
+page for more information.
+
+SDPA is used by default for `torch>=2.1.1` when an implementation is available, but you may also set
+`attn_implementation="sdpa"` in `from_pretrained()` to explicitly request SDPA to be used.
+
+```python
+from transformers import GPTNeoXForCausalLM
+model = GPTNeoXForCausalLM.from_pretrained("EleutherAI/gpt-neox-20b", torch_dtype=torch.float16, attn_implementation="sdpa")
+...
+```
+
+For the best speedups, we recommend loading the model in half-precision (e.g. `torch.float16` or `torch.bfloat16`).
+
+On a local benchmark (rtx3080ti-16GB, PyTorch 2.2.1, OS Ubuntu 22.04) using `float16` with
+[pythia-410m-deduped](https://huggingface.co/EleutherAI/pythia-410m-deduped), we saw the
+following speedups during training and inference.
+
+### Training
+| Batch size | Seq len | Time per batch (Eager - s) | Time per batch (SDPA - s) | Speedup (%) | Eager peak mem (MB) | SDPA peak mem (MB) | Mem saving (%) |
+|-----------:|-----------:|---------------------------:|-----------------------------:|------------:|--------------------:|-------------------:|------------------:|
+| 1 | 128 | 0.024 | 0.019 | 28.945 | 1789.95 | 1789.95 | 0 |
+| 1 | 256 | 0.039 | 0.031 | 23.18 | 1845.83 | 1844.84 | 0.053 |
+| 1 | 512 | 0.08 | 0.055 | 45.524 | 2278.38 | 1953.76 | 16.615 |
+| 1 | 1024 | 0.19 | 0.102 | 86.777 | 4772.36 | 2408.35 | 98.159 |
+| 1 | 2048 | 0.565 | 0.204 | 177.098 | 13484.1 | 3882.01 | 247.348 |
+| 2 | 128 | 0.037 | 0.032 | 15.121 | 1843.86 | 1844.78 | -0.05 |
+| 2 | 256 | 0.067 | 0.055 | 21.706 | 1999.72 | 1951.67 | 2.462 |
+| 2 | 512 | 0.144 | 0.096 | 50.046 | 3613.16 | 2406.77 | 50.125 |
+| 2 | 1024 | 0.366 | 0.193 | 89.666 | 8707.55 | 3878.86 | 124.487 |
+| 2 | 2048 | OOM | 0.379 | / | OOM | 6825.13 | SDPA does not OOM |
+| 4 | 128 | 0.06 | 0.054 | 11.539 | 1947.6 | 1952.06 | -0.228 |
+| 4 | 256 | 0.119 | 0.093 | 28.072 | 3008.39 | 2405.99 | 25.038 |
+| 4 | 512 | 0.275 | 0.187 | 47.145 | 6290.58 | 3877.29 | 62.242 |
+| 4 | 1024 | OOM | 0.36 | / | OOM | 6821.98 | SDPA does not OOM |
+| 4 | 2048 | OOM | 0.731 | / | OOM | 12705.1 | SDPA does not OOM |
+
+### Inference
+| Batch size | Seq len | Per token latency Eager (ms) | Per token latency SDPA (ms) | Speedup (%) | Mem Eager (MB) | Mem SDPA (MB) | Mem saved (%) |
+|--------------:|-------------:|--------------------------------:|-------------------------------:|---------------:|------------------:|----------------:|-----------------:|
+| 1 | 128 | 6.569 | 5.858 | 12.14 | 974.831 | 974.826 | 0 |
+| 1 | 256 | 7.009 | 5.863 | 19.542 | 1029.01 | 1028.08 | 0.09 |
+| 1 | 512 | 7.157 | 5.965 | 19.983 | 1137.54 | 1137.52 | 0.001 |
+| 1 | 1024 | 7.523 | 6.506 | 15.637 | 1329.3 | 1329.26 | 0.003 |
+| 1 | 2048 | 9.271 | 9.205 | 0.713 | 1752.47 | 1734.51 | 1.036 |
+| 2 | 128 | 7.239 | 5.959 | 21.493 | 1044.8 | 1028.37 | 1.597 |
+| 2 | 256 | 7.228 | 6.036 | 19.757 | 1167.32 | 1137.73 | 2.601 |
+| 2 | 512 | 7.538 | 6.693 | 12.628 | 1352.93 | 1329.55 | 1.758 |
+| 2 | 1024 | 8.916 | 8.632 | 3.291 | 1752.56 | 1734.62 | 1.034 |
+| 2 | 2048 | 12.628 | 12.606 | 0.181 | 2558.72 | 2545.8 | 0.508 |
+| 4 | 128 | 7.278 | 6.046 | 20.373 | 1168.41 | 1137.79 | 2.691 |
+| 4 | 256 | 7.614 | 6.588 | 15.574 | 1353.1 | 1329.79 | 1.753 |
+| 4 | 512 | 8.798 | 8.144 | 8.028 | 1752.76 | 1734.85 | 1.032 |
+| 4 | 1024 | 11.765 | 11.303 | 4.09 | 2558.96 | 2546.04 | 0.508 |
+| 4 | 2048 | 19.568 | 17.735 | 10.33 | 4175.5 | 4165.26 | 0.246 |
+
+
+## Resources
+
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## GPTNeoXConfig
+
+[[autodoc]] GPTNeoXConfig
+
+## GPTNeoXTokenizerFast
+
+[[autodoc]] GPTNeoXTokenizerFast
+
+## GPTNeoXModel
+
+[[autodoc]] GPTNeoXModel
+ - forward
+
+## GPTNeoXForCausalLM
+
+[[autodoc]] GPTNeoXForCausalLM
+ - forward
+
+## GPTNeoXForQuestionAnswering
+
+[[autodoc]] GPTNeoXForQuestionAnswering
+ - forward
+
+## GPTNeoXForSequenceClassification
+
+[[autodoc]] GPTNeoXForSequenceClassification
+ - forward
+
+## GPTNeoXForTokenClassification
+
+[[autodoc]] GPTNeoXForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt_neox_japanese.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt_neox_japanese.md
new file mode 100644
index 0000000000000000000000000000000000000000..c69e643cae5bd7966bd6008d32f38ddc56336f29
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt_neox_japanese.md
@@ -0,0 +1,74 @@
+
+
+# GPT-NeoX-Japanese
+
+## Overview
+
+We introduce GPT-NeoX-Japanese, which is an autoregressive language model for Japanese, trained on top of [https://github.com/EleutherAI/gpt-neox](https://github.com/EleutherAI/gpt-neox).
+Japanese is a unique language with its large vocabulary and a combination of hiragana, katakana, and kanji writing scripts.
+To address this distinct structure of the Japanese language, we use a [special sub-word tokenizer](https://github.com/tanreinama/Japanese-BPEEncoder_V2). We are very grateful to *tanreinama* for open-sourcing this incredibly helpful tokenizer.
+Following the recommendations from Google's research on [PaLM](https://ai.googleblog.com/2022/04/pathways-language-model-palm-scaling-to.html), we have removed bias parameters from transformer blocks, achieving better model performance. Please refer [this article](https://medium.com/ml-abeja/training-a-better-gpt-2-93b157662ae4) in detail.
+
+Development of the model was led by [Shinya Otani](https://github.com/SO0529), [Takayoshi Makabe](https://github.com/spider-man-tm), [Anuj Arora](https://github.com/Anuj040), and [Kyo Hattori](https://github.com/go5paopao) from [ABEJA, Inc.](https://www.abejainc.com/). For more information on this model-building activity, please refer [here (ja)](https://tech-blog.abeja.asia/entry/abeja-gpt-project-202207).
+
+### Usage example
+
+The `generate()` method can be used to generate text using GPT NeoX Japanese model.
+
+```python
+>>> from transformers import GPTNeoXJapaneseForCausalLM, GPTNeoXJapaneseTokenizer
+
+>>> model = GPTNeoXJapaneseForCausalLM.from_pretrained("abeja/gpt-neox-japanese-2.7b")
+>>> tokenizer = GPTNeoXJapaneseTokenizer.from_pretrained("abeja/gpt-neox-japanese-2.7b")
+
+>>> prompt = "人とAIが協調するためには、"
+
+>>> input_ids = tokenizer(prompt, return_tensors="pt").input_ids
+
+>>> gen_tokens = model.generate(
+... input_ids,
+... do_sample=True,
+... temperature=0.9,
+... max_length=100,
+... )
+>>> gen_text = tokenizer.batch_decode(gen_tokens, skip_special_tokens=True)[0]
+
+>>> print(gen_text)
+人とAIが協調するためには、AIと人が共存し、AIを正しく理解する必要があります。
+```
+
+## Resources
+
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## GPTNeoXJapaneseConfig
+
+[[autodoc]] GPTNeoXJapaneseConfig
+
+## GPTNeoXJapaneseTokenizer
+
+[[autodoc]] GPTNeoXJapaneseTokenizer
+
+## GPTNeoXJapaneseModel
+
+[[autodoc]] GPTNeoXJapaneseModel
+ - forward
+
+## GPTNeoXJapaneseForCausalLM
+
+[[autodoc]] GPTNeoXJapaneseForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gptj.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gptj.md
new file mode 100644
index 0000000000000000000000000000000000000000..b515cf36dd40603c18b274caabf48e9f48e101a1
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gptj.md
@@ -0,0 +1,200 @@
+
+
+# GPT-J
+
+## Overview
+
+The GPT-J model was released in the [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax) repository by Ben Wang and Aran Komatsuzaki. It is a GPT-2-like
+causal language model trained on [the Pile](https://pile.eleuther.ai/) dataset.
+
+This model was contributed by [Stella Biderman](https://huggingface.co/stellaathena).
+
+## Usage tips
+
+- To load [GPT-J](https://huggingface.co/EleutherAI/gpt-j-6B) in float32 one would need at least 2x model size
+ RAM: 1x for initial weights and another 1x to load the checkpoint. So for GPT-J it would take at least 48GB
+ RAM to just load the model. To reduce the RAM usage there are a few options. The `torch_dtype` argument can be
+ used to initialize the model in half-precision on a CUDA device only. There is also a fp16 branch which stores the fp16 weights,
+ which could be used to further minimize the RAM usage:
+
+```python
+>>> from transformers import GPTJForCausalLM
+>>> import torch
+
+>>> device = "cuda"
+>>> model = GPTJForCausalLM.from_pretrained(
+... "EleutherAI/gpt-j-6B",
+... revision="float16",
+... torch_dtype=torch.float16,
+... ).to(device)
+```
+
+- The model should fit on 16GB GPU for inference. For training/fine-tuning it would take much more GPU RAM. Adam
+ optimizer for example makes four copies of the model: model, gradients, average and squared average of the gradients.
+ So it would need at least 4x model size GPU memory, even with mixed precision as gradient updates are in fp32. This
+ is not including the activations and data batches, which would again require some more GPU RAM. So one should explore
+ solutions such as DeepSpeed, to train/fine-tune the model. Another option is to use the original codebase to
+ train/fine-tune the model on TPU and then convert the model to Transformers format for inference. Instructions for
+ that could be found [here](https://github.com/kingoflolz/mesh-transformer-jax/blob/master/howto_finetune.md)
+
+- Although the embedding matrix has a size of 50400, only 50257 entries are used by the GPT-2 tokenizer. These extra
+ tokens are added for the sake of efficiency on TPUs. To avoid the mismatch between embedding matrix size and vocab
+ size, the tokenizer for [GPT-J](https://huggingface.co/EleutherAI/gpt-j-6B) contains 143 extra tokens
+ `<|extratoken_1|>... <|extratoken_143|>`, so the `vocab_size` of tokenizer also becomes 50400.
+
+## Usage examples
+
+The [`~generation.GenerationMixin.generate`] method can be used to generate text using GPT-J
+model.
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("EleutherAI/gpt-j-6B")
+>>> tokenizer = AutoTokenizer.from_pretrained("EleutherAI/gpt-j-6B")
+
+>>> prompt = (
+... "In a shocking finding, scientists discovered a herd of unicorns living in a remote, "
+... "previously unexplored valley, in the Andes Mountains. Even more surprising to the "
+... "researchers was the fact that the unicorns spoke perfect English."
+... )
+
+>>> input_ids = tokenizer(prompt, return_tensors="pt").input_ids
+
+>>> gen_tokens = model.generate(
+... input_ids,
+... do_sample=True,
+... temperature=0.9,
+... max_length=100,
+... )
+>>> gen_text = tokenizer.batch_decode(gen_tokens)[0]
+```
+
+...or in float16 precision:
+
+```python
+>>> from transformers import GPTJForCausalLM, AutoTokenizer
+>>> import torch
+
+>>> device = "cuda"
+>>> model = GPTJForCausalLM.from_pretrained("EleutherAI/gpt-j-6B", torch_dtype=torch.float16).to(device)
+>>> tokenizer = AutoTokenizer.from_pretrained("EleutherAI/gpt-j-6B")
+
+>>> prompt = (
+... "In a shocking finding, scientists discovered a herd of unicorns living in a remote, "
+... "previously unexplored valley, in the Andes Mountains. Even more surprising to the "
+... "researchers was the fact that the unicorns spoke perfect English."
+... )
+
+>>> input_ids = tokenizer(prompt, return_tensors="pt").input_ids.to(device)
+
+>>> gen_tokens = model.generate(
+... input_ids,
+... do_sample=True,
+... temperature=0.9,
+... max_length=100,
+... )
+>>> gen_text = tokenizer.batch_decode(gen_tokens)[0]
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with GPT-J. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- Description of [GPT-J](https://huggingface.co/EleutherAI/gpt-j-6B).
+- A blog on how to [Deploy GPT-J 6B for inference using Hugging Face Transformers and Amazon SageMaker](https://huggingface.co/blog/gptj-sagemaker).
+- A blog on how to [Accelerate GPT-J inference with DeepSpeed-Inference on GPUs](https://www.philschmid.de/gptj-deepspeed-inference).
+- A blog post introducing [GPT-J-6B: 6B JAX-Based Transformer](https://arankomatsuzaki.wordpress.com/2021/06/04/gpt-j/). 🌎
+- A notebook for [GPT-J-6B Inference Demo](https://colab.research.google.com/github/kingoflolz/mesh-transformer-jax/blob/master/colab_demo.ipynb). 🌎
+- Another notebook demonstrating [Inference with GPT-J-6B](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/GPT-J-6B/Inference_with_GPT_J_6B.ipynb).
+- [Causal language modeling](https://huggingface.co/course/en/chapter7/6?fw=pt#training-a-causal-language-model-from-scratch) chapter of the 🤗 Hugging Face Course.
+- [`GPTJForCausalLM`] is supported by this [causal language modeling example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/language-modeling#gpt-2gpt-and-causal-language-modeling), [text generation example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-generation), and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb).
+- [`TFGPTJForCausalLM`] is supported by this [causal language modeling example script](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/language-modeling#run_clmpy) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb).
+- [`FlaxGPTJForCausalLM`] is supported by this [causal language modeling example script](https://github.com/huggingface/transformers/tree/main/examples/flax/language-modeling#causal-language-modeling) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/causal_language_modeling_flax.ipynb).
+
+**Documentation resources**
+- [Text classification task guide](../tasks/sequence_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## GPTJConfig
+
+[[autodoc]] GPTJConfig
+ - all
+
+
+
+
+## GPTJModel
+
+[[autodoc]] GPTJModel
+ - forward
+
+## GPTJForCausalLM
+
+[[autodoc]] GPTJForCausalLM
+ - forward
+
+## GPTJForSequenceClassification
+
+[[autodoc]] GPTJForSequenceClassification
+ - forward
+
+## GPTJForQuestionAnswering
+
+[[autodoc]] GPTJForQuestionAnswering
+ - forward
+
+
+
+
+## TFGPTJModel
+
+[[autodoc]] TFGPTJModel
+ - call
+
+## TFGPTJForCausalLM
+
+[[autodoc]] TFGPTJForCausalLM
+ - call
+
+## TFGPTJForSequenceClassification
+
+[[autodoc]] TFGPTJForSequenceClassification
+ - call
+
+## TFGPTJForQuestionAnswering
+
+[[autodoc]] TFGPTJForQuestionAnswering
+ - call
+
+
+
+
+## FlaxGPTJModel
+
+[[autodoc]] FlaxGPTJModel
+ - __call__
+
+## FlaxGPTJForCausalLM
+
+[[autodoc]] FlaxGPTJForCausalLM
+ - __call__
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gptsan-japanese.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gptsan-japanese.md
new file mode 100644
index 0000000000000000000000000000000000000000..108e59048d5d52b1a4468aaa1391643da8f420f3
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gptsan-japanese.md
@@ -0,0 +1,129 @@
+
+
+# GPTSAN-japanese
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The GPTSAN-japanese model was released in the repository by Toshiyuki Sakamoto (tanreinama).
+
+GPTSAN is a Japanese language model using Switch Transformer. It has the same structure as the model introduced as Prefix LM
+in the T5 paper, and support both Text Generation and Masked Language Modeling tasks. These basic tasks similarly can
+fine-tune for translation or summarization.
+
+### Usage example
+
+The `generate()` method can be used to generate text using GPTSAN-Japanese model.
+
+```python
+>>> from transformers import AutoModel, AutoTokenizer
+>>> import torch
+
+>>> tokenizer = AutoTokenizer.from_pretrained("Tanrei/GPTSAN-japanese")
+>>> model = AutoModel.from_pretrained("Tanrei/GPTSAN-japanese").cuda()
+>>> x_tok = tokenizer("は、", prefix_text="織田信長", return_tensors="pt")
+>>> torch.manual_seed(0)
+>>> gen_tok = model.generate(x_tok.input_ids.cuda(), token_type_ids=x_tok.token_type_ids.cuda(), max_new_tokens=20)
+>>> tokenizer.decode(gen_tok[0])
+'織田信長は、2004年に『戦国BASARA』のために、豊臣秀吉'
+```
+
+## GPTSAN Features
+
+GPTSAN has some unique features. It has a model structure of Prefix-LM. It works as a shifted Masked Language Model for Prefix Input tokens. Un-prefixed inputs behave like normal generative models.
+The Spout vector is a GPTSAN specific input. Spout is pre-trained with random inputs, but you can specify a class of text or an arbitrary vector during fine-tuning. This allows you to indicate the tendency of the generated text.
+GPTSAN has a sparse Feed Forward based on Switch-Transformer. You can also add other layers and train them partially. See the original GPTSAN repository for details.
+
+### Prefix-LM Model
+
+GPTSAN has the structure of the model named Prefix-LM in the `T5` paper. (The original GPTSAN repository calls it `hybrid`)
+In GPTSAN, the `Prefix` part of Prefix-LM, that is, the input position that can be referenced by both tokens, can be specified with any length.
+Arbitrary lengths can also be specified differently for each batch.
+This length applies to the text entered in `prefix_text` for the tokenizer.
+The tokenizer returns the mask of the `Prefix` part of Prefix-LM as `token_type_ids`.
+The model treats the part where `token_type_ids` is 1 as a `Prefix` part, that is, the input can refer to both tokens before and after.
+
+## Usage tips
+
+Specifying the Prefix part is done with a mask passed to self-attention.
+When token_type_ids=None or all zero, it is equivalent to regular causal mask
+
+for example:
+
+>>> x_token = tokenizer("アイウエ")
+input_ids: | SOT | SEG | ア | イ | ウ | エ |
+token_type_ids: | 1 | 0 | 0 | 0 | 0 | 0 |
+prefix_lm_mask:
+SOT | 1 0 0 0 0 0 |
+SEG | 1 1 0 0 0 0 |
+ア | 1 1 1 0 0 0 |
+イ | 1 1 1 1 0 0 |
+ウ | 1 1 1 1 1 0 |
+エ | 1 1 1 1 1 1 |
+
+>>> x_token = tokenizer("", prefix_text="アイウエ")
+input_ids: | SOT | ア | イ | ウ | エ | SEG |
+token_type_ids: | 1 | 1 | 1 | 1 | 1 | 0 |
+prefix_lm_mask:
+SOT | 1 1 1 1 1 0 |
+ア | 1 1 1 1 1 0 |
+イ | 1 1 1 1 1 0 |
+ウ | 1 1 1 1 1 0 |
+エ | 1 1 1 1 1 0 |
+SEG | 1 1 1 1 1 1 |
+
+>>> x_token = tokenizer("ウエ", prefix_text="アイ")
+input_ids: | SOT | ア | イ | SEG | ウ | エ |
+token_type_ids: | 1 | 1 | 1 | 0 | 0 | 0 |
+prefix_lm_mask:
+SOT | 1 1 1 0 0 0 |
+ア | 1 1 1 0 0 0 |
+イ | 1 1 1 0 0 0 |
+SEG | 1 1 1 1 0 0 |
+ウ | 1 1 1 1 1 0 |
+エ | 1 1 1 1 1 1 |
+
+### Spout Vector
+
+A Spout Vector is a special vector for controlling text generation.
+This vector is treated as the first embedding in self-attention to bring extraneous attention to the generated tokens.
+In the pre-trained model published from `Tanrei/GPTSAN-japanese`, the Spout Vector is a 128-dimensional vector that passes through 8 fully connected layers in the model and is projected into the space acting as external attention.
+The Spout Vector projected by the fully connected layer is split to be passed to all self-attentions.
+
+## GPTSanJapaneseConfig
+
+[[autodoc]] GPTSanJapaneseConfig
+
+## GPTSanJapaneseTokenizer
+
+[[autodoc]] GPTSanJapaneseTokenizer
+
+## GPTSanJapaneseModel
+
+[[autodoc]] GPTSanJapaneseModel
+
+## GPTSanJapaneseForConditionalGeneration
+
+[[autodoc]] GPTSanJapaneseForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/granite.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/granite.md
new file mode 100644
index 0000000000000000000000000000000000000000..42b6da4e74788ee225bcc866d2ae5841b978d7ec
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/granite.md
@@ -0,0 +1,74 @@
+
+
+# Granite
+
+## Overview
+
+The Granite model was proposed in [Power Scheduler: A Batch Size and Token Number Agnostic Learning Rate Scheduler](https://arxiv.org/abs/2408.13359) by Yikang Shen, Matthew Stallone, Mayank Mishra, Gaoyuan Zhang, Shawn Tan, Aditya Prasad, Adriana Meza Soria, David D. Cox and Rameswar Panda.
+
+PowerLM-3B is a 3B state-of-the-art small language model trained with the Power learning rate scheduler. It is trained on a wide range of open-source and synthetic datasets with permissive licenses. PowerLM-3B has shown promising results compared to other models in the size categories across various benchmarks, including natural language multi-choices, code generation, and math reasoning.
+
+The abstract from the paper is the following:
+
+*Finding the optimal learning rate for language model pretraining is a challenging task.
+This is not only because there is a complicated correlation between learning rate, batch size, number of training tokens, model size, and other hyperparameters but also because it is prohibitively expensive to perform a hyperparameter search for large language models with Billions or Trillions of parameters. Recent studies propose using small proxy models and small corpus to perform hyperparameter searches and transposing the optimal parameters to large models and large corpus. While the zero-shot transferability is theoretically and empirically proven for model size related hyperparameters, like depth and width, the zero-shot transfer from small corpus to large corpus is underexplored.
+In this paper, we study the correlation between optimal learning rate, batch size, and number of training tokens for the recently proposed WSD scheduler. After thousands of small experiments, we found a power-law relationship between variables and demonstrated its transferability across model sizes. Based on the observation, we propose a new learning rate scheduler, Power scheduler, that is agnostic about the number of training tokens and batch size. The experiment shows that combining the Power scheduler with Maximum Update Parameterization (\mup) can consistently achieve impressive performance with one set of hyperparameters regardless of the number of training tokens, batch size, model size, and even model architecture. Our 3B dense and MoE models trained with the Power scheduler achieve comparable performance as state-of-the-art small language models.
+We [open source](https://huggingface.co/collections/ibm/power-lm-66be64ae647ddf11b9808000) these pretrained models.*
+
+Tips:
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_path = "ibm/PowerLM-3b"
+tokenizer = AutoTokenizer.from_pretrained(model_path)
+
+# drop device_map if running on CPU
+model = AutoModelForCausalLM.from_pretrained(model_path, device_map="auto")
+model.eval()
+
+# change input text as desired
+prompt = "Write a code to find the maximum value in a list of numbers."
+
+# tokenize the text
+input_tokens = tokenizer(prompt, return_tensors="pt")
+# generate output tokens
+output = model.generate(**input_tokens, max_new_tokens=100)
+# decode output tokens into text
+output = tokenizer.batch_decode(output)
+# loop over the batch to print, in this example the batch size is 1
+for i in output:
+ print(i)
+```
+
+This model was contributed by [mayank-mishra](https://huggingface.co/mayank-mishra).
+
+
+## GraniteConfig
+
+[[autodoc]] GraniteConfig
+
+## GraniteModel
+
+[[autodoc]] GraniteModel
+ - forward
+
+## GraniteForCausalLM
+
+[[autodoc]] GraniteForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/granitemoe.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/granitemoe.md
new file mode 100644
index 0000000000000000000000000000000000000000..176e833c24c66194df748a8a553dfdeca661e7f2
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/granitemoe.md
@@ -0,0 +1,74 @@
+
+
+# GraniteMoe
+
+## Overview
+
+The GraniteMoe model was proposed in [Power Scheduler: A Batch Size and Token Number Agnostic Learning Rate Scheduler](https://arxiv.org/abs/2408.13359) by Yikang Shen, Matthew Stallone, Mayank Mishra, Gaoyuan Zhang, Shawn Tan, Aditya Prasad, Adriana Meza Soria, David D. Cox and Rameswar Panda.
+
+PowerMoE-3B is a 3B sparse Mixture-of-Experts (sMoE) language model trained with the Power learning rate scheduler. It sparsely activates 800M parameters for each token. It is trained on a mix of open-source and proprietary datasets. PowerMoE-3B has shown promising results compared to other dense models with 2x activate parameters across various benchmarks, including natural language multi-choices, code generation, and math reasoning.
+
+The abstract from the paper is the following:
+
+*Finding the optimal learning rate for language model pretraining is a challenging task.
+This is not only because there is a complicated correlation between learning rate, batch size, number of training tokens, model size, and other hyperparameters but also because it is prohibitively expensive to perform a hyperparameter search for large language models with Billions or Trillions of parameters. Recent studies propose using small proxy models and small corpus to perform hyperparameter searches and transposing the optimal parameters to large models and large corpus. While the zero-shot transferability is theoretically and empirically proven for model size related hyperparameters, like depth and width, the zero-shot transfer from small corpus to large corpus is underexplored.
+In this paper, we study the correlation between optimal learning rate, batch size, and number of training tokens for the recently proposed WSD scheduler. After thousands of small experiments, we found a power-law relationship between variables and demonstrated its transferability across model sizes. Based on the observation, we propose a new learning rate scheduler, Power scheduler, that is agnostic about the number of training tokens and batch size. The experiment shows that combining the Power scheduler with Maximum Update Parameterization (\mup) can consistently achieve impressive performance with one set of hyperparameters regardless of the number of training tokens, batch size, model size, and even model architecture. Our 3B dense and MoE models trained with the Power scheduler achieve comparable performance as state-of-the-art small language models.
+We [open source](https://huggingface.co/collections/ibm/power-lm-66be64ae647ddf11b9808000) these pretrained models.*
+
+Tips:
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_path = "ibm/PowerMoE-3b"
+tokenizer = AutoTokenizer.from_pretrained(model_path)
+
+# drop device_map if running on CPU
+model = AutoModelForCausalLM.from_pretrained(model_path, device_map="auto")
+model.eval()
+
+# change input text as desired
+prompt = "Write a code to find the maximum value in a list of numbers."
+
+# tokenize the text
+input_tokens = tokenizer(prompt, return_tensors="pt")
+# generate output tokens
+output = model.generate(**input_tokens, max_new_tokens=100)
+# decode output tokens into text
+output = tokenizer.batch_decode(output)
+# loop over the batch to print, in this example the batch size is 1
+for i in output:
+ print(i)
+```
+
+This model was contributed by [mayank-mishra](https://huggingface.co/mayank-mishra).
+
+
+## GraniteMoeConfig
+
+[[autodoc]] GraniteMoeConfig
+
+## GraniteMoeModel
+
+[[autodoc]] GraniteMoeModel
+ - forward
+
+## GraniteMoeForCausalLM
+
+[[autodoc]] GraniteMoeForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/graphormer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/graphormer.md
new file mode 100644
index 0000000000000000000000000000000000000000..d01bf04debf9dd3aa9c837b5df06bc2683468fca
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/graphormer.md
@@ -0,0 +1,55 @@
+
+
+# Graphormer
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The Graphormer model was proposed in [Do Transformers Really Perform Bad for Graph Representation?](https://arxiv.org/abs/2106.05234) by
+Chengxuan Ying, Tianle Cai, Shengjie Luo, Shuxin Zheng, Guolin Ke, Di He, Yanming Shen and Tie-Yan Liu. It is a Graph Transformer model, modified to allow computations on graphs instead of text sequences by generating embeddings and features of interest during preprocessing and collation, then using a modified attention.
+
+The abstract from the paper is the following:
+
+*The Transformer architecture has become a dominant choice in many domains, such as natural language processing and computer vision. Yet, it has not achieved competitive performance on popular leaderboards of graph-level prediction compared to mainstream GNN variants. Therefore, it remains a mystery how Transformers could perform well for graph representation learning. In this paper, we solve this mystery by presenting Graphormer, which is built upon the standard Transformer architecture, and could attain excellent results on a broad range of graph representation learning tasks, especially on the recent OGB Large-Scale Challenge. Our key insight to utilizing Transformer in the graph is the necessity of effectively encoding the structural information of a graph into the model. To this end, we propose several simple yet effective structural encoding methods to help Graphormer better model graph-structured data. Besides, we mathematically characterize the expressive power of Graphormer and exhibit that with our ways of encoding the structural information of graphs, many popular GNN variants could be covered as the special cases of Graphormer.*
+
+This model was contributed by [clefourrier](https://huggingface.co/clefourrier). The original code can be found [here](https://github.com/microsoft/Graphormer).
+
+## Usage tips
+
+This model will not work well on large graphs (more than 100 nodes/edges), as it will make the memory explode.
+You can reduce the batch size, increase your RAM, or decrease the `UNREACHABLE_NODE_DISTANCE` parameter in algos_graphormer.pyx, but it will be hard to go above 700 nodes/edges.
+
+This model does not use a tokenizer, but instead a special collator during training.
+
+## GraphormerConfig
+
+[[autodoc]] GraphormerConfig
+
+## GraphormerModel
+
+[[autodoc]] GraphormerModel
+ - forward
+
+## GraphormerForGraphClassification
+
+[[autodoc]] GraphormerForGraphClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/grounding-dino.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/grounding-dino.md
new file mode 100644
index 0000000000000000000000000000000000000000..a6da554f8d50531cb64b18c5f06e850422044420
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/grounding-dino.md
@@ -0,0 +1,118 @@
+
+
+# Grounding DINO
+
+## Overview
+
+The Grounding DINO model was proposed in [Grounding DINO: Marrying DINO with Grounded Pre-Training for Open-Set Object Detection](https://arxiv.org/abs/2303.05499) by Shilong Liu, Zhaoyang Zeng, Tianhe Ren, Feng Li, Hao Zhang, Jie Yang, Chunyuan Li, Jianwei Yang, Hang Su, Jun Zhu, Lei Zhang. Grounding DINO extends a closed-set object detection model with a text encoder, enabling open-set object detection. The model achieves remarkable results, such as 52.5 AP on COCO zero-shot.
+
+The abstract from the paper is the following:
+
+*In this paper, we present an open-set object detector, called Grounding DINO, by marrying Transformer-based detector DINO with grounded pre-training, which can detect arbitrary objects with human inputs such as category names or referring expressions. The key solution of open-set object detection is introducing language to a closed-set detector for open-set concept generalization. To effectively fuse language and vision modalities, we conceptually divide a closed-set detector into three phases and propose a tight fusion solution, which includes a feature enhancer, a language-guided query selection, and a cross-modality decoder for cross-modality fusion. While previous works mainly evaluate open-set object detection on novel categories, we propose to also perform evaluations on referring expression comprehension for objects specified with attributes. Grounding DINO performs remarkably well on all three settings, including benchmarks on COCO, LVIS, ODinW, and RefCOCO/+/g. Grounding DINO achieves a 52.5 AP on the COCO detection zero-shot transfer benchmark, i.e., without any training data from COCO. It sets a new record on the ODinW zero-shot benchmark with a mean 26.1 AP.*
+
+
+
+ Grounding DINO overview. Taken from the original paper.
+
+This model was contributed by [EduardoPacheco](https://huggingface.co/EduardoPacheco) and [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/IDEA-Research/GroundingDINO).
+
+## Usage tips
+
+- One can use [`GroundingDinoProcessor`] to prepare image-text pairs for the model.
+- To separate classes in the text use a period e.g. "a cat. a dog."
+- When using multiple classes (e.g. `"a cat. a dog."`), use `post_process_grounded_object_detection` from [`GroundingDinoProcessor`] to post process outputs. Since, the labels returned from `post_process_object_detection` represent the indices from the model dimension where prob > threshold.
+
+Here's how to use the model for zero-shot object detection:
+
+```python
+>>> import requests
+
+>>> import torch
+>>> from PIL import Image
+>>> from transformers import AutoProcessor, AutoModelForZeroShotObjectDetection
+
+>>> model_id = "IDEA-Research/grounding-dino-tiny"
+>>> device = "cuda"
+
+>>> processor = AutoProcessor.from_pretrained(model_id)
+>>> model = AutoModelForZeroShotObjectDetection.from_pretrained(model_id).to(device)
+
+>>> image_url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(image_url, stream=True).raw)
+>>> # Check for cats and remote controls
+>>> text = "a cat. a remote control."
+
+>>> inputs = processor(images=image, text=text, return_tensors="pt").to(device)
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> results = processor.post_process_grounded_object_detection(
+... outputs,
+... inputs.input_ids,
+... box_threshold=0.4,
+... text_threshold=0.3,
+... target_sizes=[image.size[::-1]]
+... )
+>>> print(results)
+[{'boxes': tensor([[344.6959, 23.1090, 637.1833, 374.2751],
+ [ 12.2666, 51.9145, 316.8582, 472.4392],
+ [ 38.5742, 70.0015, 176.7838, 118.1806]], device='cuda:0'),
+ 'labels': ['a cat', 'a cat', 'a remote control'],
+ 'scores': tensor([0.4785, 0.4381, 0.4776], device='cuda:0')}]
+```
+
+## Grounded SAM
+
+One can combine Grounding DINO with the [Segment Anything](sam) model for text-based mask generation as introduced in [Grounded SAM: Assembling Open-World Models for Diverse Visual Tasks](https://arxiv.org/abs/2401.14159). You can refer to this [demo notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/Grounding%20DINO/GroundingDINO_with_Segment_Anything.ipynb) 🌍 for details.
+
+
+
+ Grounded SAM overview. Taken from the original repository.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Grounding DINO. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- Demo notebooks regarding inference with Grounding DINO as well as combining it with [SAM](sam) can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Grounding%20DINO). 🌎
+
+## GroundingDinoImageProcessor
+
+[[autodoc]] GroundingDinoImageProcessor
+ - preprocess
+ - post_process_object_detection
+
+## GroundingDinoProcessor
+
+[[autodoc]] GroundingDinoProcessor
+ - post_process_grounded_object_detection
+
+## GroundingDinoConfig
+
+[[autodoc]] GroundingDinoConfig
+
+## GroundingDinoModel
+
+[[autodoc]] GroundingDinoModel
+ - forward
+
+## GroundingDinoForObjectDetection
+
+[[autodoc]] GroundingDinoForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/groupvit.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/groupvit.md
new file mode 100644
index 0000000000000000000000000000000000000000..8728cf0da21ba2909abd50fddf48a821707d2f7f
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/groupvit.md
@@ -0,0 +1,96 @@
+
+
+# GroupViT
+
+## Overview
+
+The GroupViT model was proposed in [GroupViT: Semantic Segmentation Emerges from Text Supervision](https://arxiv.org/abs/2202.11094) by Jiarui Xu, Shalini De Mello, Sifei Liu, Wonmin Byeon, Thomas Breuel, Jan Kautz, Xiaolong Wang.
+Inspired by [CLIP](clip), GroupViT is a vision-language model that can perform zero-shot semantic segmentation on any given vocabulary categories.
+
+The abstract from the paper is the following:
+
+*Grouping and recognition are important components of visual scene understanding, e.g., for object detection and semantic segmentation. With end-to-end deep learning systems, grouping of image regions usually happens implicitly via top-down supervision from pixel-level recognition labels. Instead, in this paper, we propose to bring back the grouping mechanism into deep networks, which allows semantic segments to emerge automatically with only text supervision. We propose a hierarchical Grouping Vision Transformer (GroupViT), which goes beyond the regular grid structure representation and learns to group image regions into progressively larger arbitrary-shaped segments. We train GroupViT jointly with a text encoder on a large-scale image-text dataset via contrastive losses. With only text supervision and without any pixel-level annotations, GroupViT learns to group together semantic regions and successfully transfers to the task of semantic segmentation in a zero-shot manner, i.e., without any further fine-tuning. It achieves a zero-shot accuracy of 52.3% mIoU on the PASCAL VOC 2012 and 22.4% mIoU on PASCAL Context datasets, and performs competitively to state-of-the-art transfer-learning methods requiring greater levels of supervision.*
+
+This model was contributed by [xvjiarui](https://huggingface.co/xvjiarui). The TensorFlow version was contributed by [ariG23498](https://huggingface.co/ariG23498) with the help of [Yih-Dar SHIEH](https://huggingface.co/ydshieh), [Amy Roberts](https://huggingface.co/amyeroberts), and [Joao Gante](https://huggingface.co/joaogante).
+The original code can be found [here](https://github.com/NVlabs/GroupViT).
+
+## Usage tips
+
+- You may specify `output_segmentation=True` in the forward of `GroupViTModel` to get the segmentation logits of input texts.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with GroupViT.
+
+- The quickest way to get started with GroupViT is by checking the [example notebooks](https://github.com/xvjiarui/GroupViT/blob/main/demo/GroupViT_hf_inference_notebook.ipynb) (which showcase zero-shot segmentation inference).
+- One can also check out the [HuggingFace Spaces demo](https://huggingface.co/spaces/xvjiarui/GroupViT) to play with GroupViT.
+
+## GroupViTConfig
+
+[[autodoc]] GroupViTConfig
+ - from_text_vision_configs
+
+## GroupViTTextConfig
+
+[[autodoc]] GroupViTTextConfig
+
+## GroupViTVisionConfig
+
+[[autodoc]] GroupViTVisionConfig
+
+
+
+
+## GroupViTModel
+
+[[autodoc]] GroupViTModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## GroupViTTextModel
+
+[[autodoc]] GroupViTTextModel
+ - forward
+
+## GroupViTVisionModel
+
+[[autodoc]] GroupViTVisionModel
+ - forward
+
+
+
+
+## TFGroupViTModel
+
+[[autodoc]] TFGroupViTModel
+ - call
+ - get_text_features
+ - get_image_features
+
+## TFGroupViTTextModel
+
+[[autodoc]] TFGroupViTTextModel
+ - call
+
+## TFGroupViTVisionModel
+
+[[autodoc]] TFGroupViTVisionModel
+ - call
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/herbert.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/herbert.md
new file mode 100644
index 0000000000000000000000000000000000000000..0049d6bfcf3a2bab66706caf65f0e0c42535a67d
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/herbert.md
@@ -0,0 +1,76 @@
+
+
+# HerBERT
+
+## Overview
+
+The HerBERT model was proposed in [KLEJ: Comprehensive Benchmark for Polish Language Understanding](https://www.aclweb.org/anthology/2020.acl-main.111.pdf) by Piotr Rybak, Robert Mroczkowski, Janusz Tracz, and
+Ireneusz Gawlik. It is a BERT-based Language Model trained on Polish Corpora using only MLM objective with dynamic
+masking of whole words.
+
+The abstract from the paper is the following:
+
+*In recent years, a series of Transformer-based models unlocked major improvements in general natural language
+understanding (NLU) tasks. Such a fast pace of research would not be possible without general NLU benchmarks, which
+allow for a fair comparison of the proposed methods. However, such benchmarks are available only for a handful of
+languages. To alleviate this issue, we introduce a comprehensive multi-task benchmark for the Polish language
+understanding, accompanied by an online leaderboard. It consists of a diverse set of tasks, adopted from existing
+datasets for named entity recognition, question-answering, textual entailment, and others. We also introduce a new
+sentiment analysis task for the e-commerce domain, named Allegro Reviews (AR). To ensure a common evaluation scheme and
+promote models that generalize to different NLU tasks, the benchmark includes datasets from varying domains and
+applications. Additionally, we release HerBERT, a Transformer-based model trained specifically for the Polish language,
+which has the best average performance and obtains the best results for three out of nine tasks. Finally, we provide an
+extensive evaluation, including several standard baselines and recently proposed, multilingual Transformer-based
+models.*
+
+This model was contributed by [rmroczkowski](https://huggingface.co/rmroczkowski). The original code can be found
+[here](https://github.com/allegro/HerBERT).
+
+
+## Usage example
+
+```python
+>>> from transformers import HerbertTokenizer, RobertaModel
+
+>>> tokenizer = HerbertTokenizer.from_pretrained("allegro/herbert-klej-cased-tokenizer-v1")
+>>> model = RobertaModel.from_pretrained("allegro/herbert-klej-cased-v1")
+
+>>> encoded_input = tokenizer.encode("Kto ma lepszą sztukę, ma lepszy rząd – to jasne.", return_tensors="pt")
+>>> outputs = model(encoded_input)
+
+>>> # HerBERT can also be loaded using AutoTokenizer and AutoModel:
+>>> import torch
+>>> from transformers import AutoModel, AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("allegro/herbert-klej-cased-tokenizer-v1")
+>>> model = AutoModel.from_pretrained("allegro/herbert-klej-cased-v1")
+```
+
+
+
+Herbert implementation is the same as `BERT` except for the tokenization method. Refer to [BERT documentation](bert)
+for API reference and examples.
+
+
+
+## HerbertTokenizer
+
+[[autodoc]] HerbertTokenizer
+
+## HerbertTokenizerFast
+
+[[autodoc]] HerbertTokenizerFast
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/hiera.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/hiera.md
new file mode 100644
index 0000000000000000000000000000000000000000..c63c892c7c7d07660d79328c0366730658553349
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/hiera.md
@@ -0,0 +1,62 @@
+
+
+# Hiera
+
+## Overview
+
+Hiera was proposed in [Hiera: A Hierarchical Vision Transformer without the Bells-and-Whistles](https://arxiv.org/abs/2306.00989) by Chaitanya Ryali, Yuan-Ting Hu, Daniel Bolya, Chen Wei, Haoqi Fan, Po-Yao Huang, Vaibhav Aggarwal, Arkabandhu Chowdhury, Omid Poursaeed, Judy Hoffman, Jitendra Malik, Yanghao Li, Christoph Feichtenhofer
+
+The paper introduces "Hiera," a hierarchical Vision Transformer that simplifies the architecture of modern hierarchical vision transformers by removing unnecessary components without compromising on accuracy or efficiency. Unlike traditional transformers that add complex vision-specific components to improve supervised classification performance, Hiera demonstrates that such additions, often termed "bells-and-whistles," are not essential for high accuracy. By leveraging a strong visual pretext task (MAE) for pretraining, Hiera retains simplicity and achieves superior accuracy and speed both in inference and training across various image and video recognition tasks. The approach suggests that spatial biases required for vision tasks can be effectively learned through proper pretraining, eliminating the need for added architectural complexity.
+
+The abstract from the paper is the following:
+
+*Modern hierarchical vision transformers have added several vision-specific components in the pursuit of supervised classification performance. While these components lead to effective accuracies and attractive FLOP counts, the added complexity actually makes these transformers slower than their vanilla ViT counterparts. In this paper, we argue that this additional bulk is unnecessary. By pretraining with a strong visual pretext task (MAE), we can strip out all the bells-and-whistles from a state-of-the-art multi-stage vision transformer without losing accuracy. In the process, we create Hiera, an extremely simple hierarchical vision transformer that is more accurate than previous models while being significantly faster both at inference and during training. We evaluate Hiera on a variety of tasks for image and video recognition. Our code and models are available at https://github.com/facebookresearch/hiera.*
+
+
+
+ Hiera architecture. Taken from the original paper.
+
+This model was a joint contribution by [EduardoPacheco](https://huggingface.co/EduardoPacheco) and [namangarg110](https://huggingface.co/namangarg110). The original code can be found [here] (https://github.com/facebookresearch/hiera).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Hiera. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- [`HieraForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+## HieraConfig
+
+[[autodoc]] HieraConfig
+
+## HieraModel
+
+[[autodoc]] HieraModel
+ - forward
+
+## HieraForPreTraining
+
+[[autodoc]] HieraForPreTraining
+ - forward
+
+## HieraForImageClassification
+
+[[autodoc]] HieraForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/hubert.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/hubert.md
new file mode 100644
index 0000000000000000000000000000000000000000..93e40d4f4ee895c8c0e74f29c4a9830951470700
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/hubert.md
@@ -0,0 +1,124 @@
+
+
+# Hubert
+
+## Overview
+
+Hubert was proposed in [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://arxiv.org/abs/2106.07447) by Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan
+Salakhutdinov, Abdelrahman Mohamed.
+
+The abstract from the paper is the following:
+
+*Self-supervised approaches for speech representation learning are challenged by three unique problems: (1) there are
+multiple sound units in each input utterance, (2) there is no lexicon of input sound units during the pre-training
+phase, and (3) sound units have variable lengths with no explicit segmentation. To deal with these three problems, we
+propose the Hidden-Unit BERT (HuBERT) approach for self-supervised speech representation learning, which utilizes an
+offline clustering step to provide aligned target labels for a BERT-like prediction loss. A key ingredient of our
+approach is applying the prediction loss over the masked regions only, which forces the model to learn a combined
+acoustic and language model over the continuous inputs. HuBERT relies primarily on the consistency of the unsupervised
+clustering step rather than the intrinsic quality of the assigned cluster labels. Starting with a simple k-means
+teacher of 100 clusters, and using two iterations of clustering, the HuBERT model either matches or improves upon the
+state-of-the-art wav2vec 2.0 performance on the Librispeech (960h) and Libri-light (60,000h) benchmarks with 10min, 1h,
+10h, 100h, and 960h fine-tuning subsets. Using a 1B parameter model, HuBERT shows up to 19% and 13% relative WER
+reduction on the more challenging dev-other and test-other evaluation subsets.*
+
+This model was contributed by [patrickvonplaten](https://huggingface.co/patrickvonplaten).
+
+# Usage tips
+
+- Hubert is a speech model that accepts a float array corresponding to the raw waveform of the speech signal.
+- Hubert model was fine-tuned using connectionist temporal classification (CTC) so the model output has to be decoded
+ using [`Wav2Vec2CTCTokenizer`].
+
+
+## Using Flash Attention 2
+
+Flash Attention 2 is an faster, optimized version of the model.
+
+### Installation
+
+First, check whether your hardware is compatible with Flash Attention 2. The latest list of compatible hardware can be found in the [official documentation](https://github.com/Dao-AILab/flash-attention#installation-and-features). If your hardware is not compatible with Flash Attention 2, you can still benefit from attention kernel optimisations through Better Transformer support covered [above](https://huggingface.co/docs/transformers/main/en/model_doc/bark#using-better-transformer).
+
+Next, [install](https://github.com/Dao-AILab/flash-attention#installation-and-features) the latest version of Flash Attention 2:
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+### Usage
+
+Below is an expected speedup diagram comparing the pure inference time between the native implementation in transformers of `facebook/hubert-large-ls960-ft`, the flash-attention-2 and the sdpa (scale-dot-product-attention) version. We show the average speedup obtained on the `librispeech_asr` `clean` validation split:
+
+```python
+>>> from transformers import Wav2Vec2Model
+
+model = Wav2Vec2Model.from_pretrained("facebook/hubert-large-ls960-ft", torch_dtype=torch.float16, attn_implementation="flash_attention_2").to(device)
+...
+```
+
+### Expected speedups
+
+Below is an expected speedup diagram comparing the pure inference time between the native implementation in transformers of the `facebook/hubert-large-ls960-ft` model and the flash-attention-2 and sdpa (scale-dot-product-attention) versions. . We show the average speedup obtained on the `librispeech_asr` `clean` validation split:
+
+
+
+
+
+
+
+## Resources
+
+- [Audio classification task guide](../tasks/audio_classification)
+- [Automatic speech recognition task guide](../tasks/asr)
+
+## HubertConfig
+
+[[autodoc]] HubertConfig
+
+
+
+
+## HubertModel
+
+[[autodoc]] HubertModel
+ - forward
+
+## HubertForCTC
+
+[[autodoc]] HubertForCTC
+ - forward
+
+## HubertForSequenceClassification
+
+[[autodoc]] HubertForSequenceClassification
+ - forward
+
+
+
+
+## TFHubertModel
+
+[[autodoc]] TFHubertModel
+ - call
+
+## TFHubertForCTC
+
+[[autodoc]] TFHubertForCTC
+ - call
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/ibert.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/ibert.md
new file mode 100644
index 0000000000000000000000000000000000000000..9ea623951aec8e480268a55cccddbdb33ddb4c55
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/ibert.md
@@ -0,0 +1,83 @@
+
+
+# I-BERT
+
+## Overview
+
+The I-BERT model was proposed in [I-BERT: Integer-only BERT Quantization](https://arxiv.org/abs/2101.01321) by
+Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney and Kurt Keutzer. It's a quantized version of RoBERTa running
+inference up to four times faster.
+
+The abstract from the paper is the following:
+
+*Transformer based models, like BERT and RoBERTa, have achieved state-of-the-art results in many Natural Language
+Processing tasks. However, their memory footprint, inference latency, and power consumption are prohibitive for
+efficient inference at the edge, and even at the data center. While quantization can be a viable solution for this,
+previous work on quantizing Transformer based models use floating-point arithmetic during inference, which cannot
+efficiently utilize integer-only logical units such as the recent Turing Tensor Cores, or traditional integer-only ARM
+processors. In this work, we propose I-BERT, a novel quantization scheme for Transformer based models that quantizes
+the entire inference with integer-only arithmetic. Based on lightweight integer-only approximation methods for
+nonlinear operations, e.g., GELU, Softmax, and Layer Normalization, I-BERT performs an end-to-end integer-only BERT
+inference without any floating point calculation. We evaluate our approach on GLUE downstream tasks using
+RoBERTa-Base/Large. We show that for both cases, I-BERT achieves similar (and slightly higher) accuracy as compared to
+the full-precision baseline. Furthermore, our preliminary implementation of I-BERT shows a speedup of 2.4 - 4.0x for
+INT8 inference on a T4 GPU system as compared to FP32 inference. The framework has been developed in PyTorch and has
+been open-sourced.*
+
+This model was contributed by [kssteven](https://huggingface.co/kssteven). The original code can be found [here](https://github.com/kssteven418/I-BERT).
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/masked_language_modeling)
+
+## IBertConfig
+
+[[autodoc]] IBertConfig
+
+## IBertModel
+
+[[autodoc]] IBertModel
+ - forward
+
+## IBertForMaskedLM
+
+[[autodoc]] IBertForMaskedLM
+ - forward
+
+## IBertForSequenceClassification
+
+[[autodoc]] IBertForSequenceClassification
+ - forward
+
+## IBertForMultipleChoice
+
+[[autodoc]] IBertForMultipleChoice
+ - forward
+
+## IBertForTokenClassification
+
+[[autodoc]] IBertForTokenClassification
+ - forward
+
+## IBertForQuestionAnswering
+
+[[autodoc]] IBertForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/idefics.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/idefics.md
new file mode 100644
index 0000000000000000000000000000000000000000..ab66bd555a71d5937d6414e6a543a29fa696004e
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/idefics.md
@@ -0,0 +1,73 @@
+
+
+# IDEFICS
+
+## Overview
+
+The IDEFICS model was proposed in [OBELICS: An Open Web-Scale Filtered Dataset of Interleaved Image-Text Documents
+](https://huggingface.co/papers/2306.16527
+) by Hugo Laurençon, Lucile Saulnier, Léo Tronchon, Stas Bekman, Amanpreet Singh, Anton Lozhkov, Thomas Wang, Siddharth Karamcheti, Alexander M. Rush, Douwe Kiela, Matthieu Cord, Victor Sanh
+
+The abstract from the paper is the following:
+
+*Large multimodal models trained on natural documents, which interleave images and text, outperform models trained on image-text pairs on various multimodal benchmarks that require reasoning over one or multiple images to generate a text. However, the datasets used to train these models have not been released, and the collection process has not been fully specified. We introduce the OBELICS dataset, an open web-scale filtered dataset of interleaved image-text documents comprising 141 million web pages extracted from Common Crawl, 353 million associated images, and 115 billion text tokens. We describe the dataset creation process, present comprehensive filtering rules, and provide an analysis of the dataset's content. To show the viability of OBELISC, we train an 80 billion parameters vision and language model on the dataset and obtain competitive performance on various multimodal benchmarks. We release the code to reproduce the dataset along with the dataset itself.*
+
+This model was contributed by [HuggingFaceM4](https://huggingface.co/HuggingFaceM4). The original code can be found [here](). (TODO: don't have a public link yet).
+
+
+
+
+IDEFICS modeling code in Transformers is for finetuning and inferencing the pre-trained IDEFICS models.
+
+To train a new IDEFICS model from scratch use the m4 codebase (a link will be provided once it's made public)
+
+
+
+
+## IdeficsConfig
+
+[[autodoc]] IdeficsConfig
+
+## IdeficsModel
+
+[[autodoc]] IdeficsModel
+ - forward
+
+## IdeficsForVisionText2Text
+
+[[autodoc]] IdeficsForVisionText2Text
+ - forward
+
+## TFIdeficsModel
+
+[[autodoc]] TFIdeficsModel
+ - call
+
+## TFIdeficsForVisionText2Text
+
+[[autodoc]] TFIdeficsForVisionText2Text
+ - call
+
+## IdeficsImageProcessor
+
+[[autodoc]] IdeficsImageProcessor
+ - preprocess
+
+## IdeficsProcessor
+
+[[autodoc]] IdeficsProcessor
+ - __call__
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/idefics2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/idefics2.md
new file mode 100644
index 0000000000000000000000000000000000000000..b9b51082f29e5b3f0ec436178b675524b9d745a0
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/idefics2.md
@@ -0,0 +1,218 @@
+
+
+# Idefics2
+
+## Overview
+
+The Idefics2 model was proposed in [What matters when building vision-language models?](https://arxiv.org/abs/2405.02246) by Léo Tronchon, Hugo Laurencon, Victor Sanh. The accompanying blog post can be found [here](https://huggingface.co/blog/idefics2).
+
+Idefics2 is an open multimodal model that accepts arbitrary sequences of image and text inputs and produces text
+outputs. The model can answer questions about images, describe visual content, create stories grounded on multiple
+images, or simply behave as a pure language model without visual inputs. It improves upon IDEFICS-1, notably on
+document understanding, OCR, or visual reasoning. Idefics2 is lightweight (8 billion parameters) and treats
+images in their native aspect ratio and resolution, which allows for varying inference efficiency.
+
+The abstract from the paper is the following:
+
+*The growing interest in vision-language models (VLMs) has been driven by improvements in large language models and vision transformers. Despite the abundance of literature on this subject, we observe that critical decisions regarding the design of VLMs are often not justified. We argue that these unsupported decisions impede progress in the field by making it difficult to identify which choices improve model performance. To address this issue, we conduct extensive experiments around pre-trained models, architecture choice, data, and training methods. Our consolidation of findings includes the development of Idefics2, an efficient foundational VLM of 8 billion parameters. Idefics2 achieves state-of-the-art performance within its size category across various multimodal benchmarks, and is often on par with models four times its size. We release the model (base, instructed, and chat) along with the datasets created for its training.*
+
+
+
+ Idefics2 architecture. Taken from the original paper.
+
+This model was contributed by [amyeroberts](https://huggingface.co/amyeroberts).
+The original code can be found [here](https://huggingface.co/HuggingFaceM4/idefics2).
+
+## Usage tips
+
+- Each sample can contain multiple images, and the number of images can vary between samples. The processor will pad the inputs to the maximum number of images in a batch for input to the model.
+- The processor has a `do_image_splitting` option. If `True`, each input image will be split into 4 sub-images, and concatenated with the original to form 5 images. This is useful for increasing model performance. Make sure `processor.image_processor.do_image_splitting` is set to `False` if the model was not trained with this option.
+- `text` passed to the processor should have the `` tokens where the images should be inserted. And `` at the end of each utterance if the text is a chat message.
+- The processor has its own `apply_chat_template` method to convert chat messages to text that can then be passed as `text` to the processor.
+
+Example of how to use the processor on chat messages:
+
+```python
+import requests
+from PIL import Image
+from transformers import Idefics2Processor, Idefics2ForConditionalGeneration
+import torch
+
+device = "cuda" if torch.cuda.is_available() else "cpu"
+
+url_1 = "http://images.cocodataset.org/val2017/000000039769.jpg"
+url_2 = "http://images.cocodataset.org/val2017/000000219578.jpg"
+
+image_1 = Image.open(requests.get(url_1, stream=True).raw)
+image_2 = Image.open(requests.get(url_2, stream=True).raw)
+images = [image_1, image_2]
+
+messages = [{
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "What’s the difference between these two images?"},
+ {"type": "image"},
+ {"type": "image"},
+ ],
+}]
+
+processor = Idefics2Processor.from_pretrained("HuggingFaceM4/idefics2-8b")
+model = Idefics2ForConditionalGeneration.from_pretrained("HuggingFaceM4/idefics2-8b")
+model.to(device)
+
+# at inference time, one needs to pass `add_generation_prompt=True` in order to make sure the model completes the prompt
+text = processor.apply_chat_template(messages, add_generation_prompt=True)
+print(text)
+# 'User: What’s the difference between these two images?\nAssistant:'
+
+inputs = processor(images=images, text=text, return_tensors="pt").to(device)
+
+generated_text = model.generate(**inputs, max_new_tokens=500)
+generated_text = processor.batch_decode(generated_text, skip_special_tokens=True)[0]
+print("Generated text:", generated_text)
+```
+
+- During training, it's important to determine which tokens the model should not learn. For Idefics2, this typically comes down to the image and padding tokens. This means that one can create the labels as follows:
+
+```python
+import requests
+from PIL import Image
+from transformers import Idefics2Processor, Idefics2ForConditionalGeneration
+import torch
+
+url_1 = "http://images.cocodataset.org/val2017/000000039769.jpg"
+url_2 = "http://images.cocodataset.org/val2017/000000219578.jpg"
+
+image_1 = Image.open(requests.get(url_1, stream=True).raw)
+image_2 = Image.open(requests.get(url_2, stream=True).raw)
+images = [image_1, image_2]
+
+messages = [{
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "What’s the difference between these two images?"},
+ {"type": "image"},
+ {"type": "image"},
+ ],
+},
+{
+ "role": "assistant",
+ "content": [
+ {"type": "text", "text": "The difference is that one image is about dogs and the other one about cats."},
+ ],
+}]
+
+device = "cuda" if torch.cuda.is_available() else "cpu"
+
+processor = Idefics2Processor.from_pretrained("HuggingFaceM4/idefics2-8b")
+model = Idefics2ForConditionalGeneration.from_pretrained("HuggingFaceM4/idefics2-8b")
+model.to(device)
+
+text = processor.apply_chat_template(messages, add_generation_prompt=False)
+inputs = processor(images=images, text=text, return_tensors="pt").to(device)
+
+labels = inputs.input_ids.clone()
+labels[labels == processor.tokenizer.pad_token_id] = -100
+labels[labels == model.config.image_token_id] = -100
+
+inputs["labels"] = labels
+
+outputs = model(**inputs)
+loss = outputs.loss
+loss.backward()
+```
+
+Do note that when training Idefics2 on multi-turn conversations between a user and an assistant, one typically also sets all the tokens corresponding to the user messages to -100.
+
+## Model optimizations: Flash Attention
+
+The code snippets above showcase inference without any optimization tricks. However, one can drastically speed up the model by leveraging [Flash Attention](../perf_train_gpu_one#flash-attention-2), which is a faster implementation of the attention mechanism used inside the model.
+
+First, make sure to install the latest version of Flash Attention 2 to include the sliding window attention feature.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Make also sure that you have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of the [flash attention repository](https://github.com/Dao-AILab/flash-attention). Make also sure to load your model in half-precision (e.g. `torch.float16`)
+
+To load and run a model using Flash Attention-2, simply change the code snippet above with the following change:
+
+```diff
+model = Idefics2ForConditionalGeneration.from_pretrained(
+ "HuggingFaceM4/idefics2-8b",
++ torch_dtype=torch.float16,
++ attn_implementation="flash_attention_2",
+).to(device)
+```
+
+## Shrinking down Idefics2 using quantization
+
+As the Idefics2 model has 8 billion parameters, that would require about 16GB of GPU RAM in half precision (float16), since each parameter is stored in 2 bytes. However, one can shrink down the size of the model using [quantization](../quantization.md). If the model is quantized to 4 bits (or half a byte per parameter), that requires only about 3.5GB of RAM.
+
+Quantizing a model is as simple as passing a `quantization_config` to the model. One can change the code snippet above with the changes below. We'll leverage the BitsAndyBytes quantization (but refer to [this page](../quantization.md) for other quantization methods):
+
+```diff
++ from transformers import BitsAndBytesConfig
+
++ quantization_config = BitsAndBytesConfig(
++ load_in_4bit=True,
++ bnb_4bit_quant_type="nf4",
++ bnb_4bit_use_double_quant=True,
++ bnb_4bit_compute_dtype=torch.float16
++ )
+model = Idefics2ForConditionalGeneration.from_pretrained(
+ "HuggingFaceM4/idefics2-8b",
++ torch_dtype=torch.float16,
++ quantization_config=quantization_config,
+).to(device)
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Idefics2. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- A notebook on how to fine-tune Idefics2 on a custom dataset using the [Trainer](../main_classes/trainer.md) can be found [here](https://colab.research.google.com/drive/1NtcTgRbSBKN7pYD3Vdx1j9m8pt3fhFDB?usp=sharing). It supports both full fine-tuning as well as (quantized) LoRa.
+- A script regarding how to fine-tune Idefics2 using the TRL library can be found [here](https://gist.github.com/edbeeching/228652fc6c2b29a1641be5a5778223cb).
+- Demo notebook regarding fine-tuning Idefics2 for JSON extraction use cases can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Idefics2). 🌎
+
+## Idefics2Config
+
+[[autodoc]] Idefics2Config
+
+
+## Idefics2Model
+
+[[autodoc]] Idefics2Model
+ - forward
+
+
+## Idefics2ForConditionalGeneration
+
+[[autodoc]] Idefics2ForConditionalGeneration
+ - forward
+
+
+## Idefics2ImageProcessor
+[[autodoc]] Idefics2ImageProcessor
+ - preprocess
+
+
+## Idefics2Processor
+[[autodoc]] Idefics2Processor
+ - __call__
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/idefics3.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/idefics3.md
new file mode 100644
index 0000000000000000000000000000000000000000..cf7c043e9289019db2fe04b0907140014a76f2f2
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/idefics3.md
@@ -0,0 +1,80 @@
+
+
+# Idefics3
+
+## Overview
+
+The Idefics3 model was proposed in [Building and better understanding vision-language models: insights and future directions](https://huggingface.co/papers/2408.12637) by Hugo Laurençon, Andrés Marafioti, Victor Sanh, and Léo Tronchon.
+
+Idefics3 is an adaptation of the Idefics2 model with three main differences:
+
+- It uses Llama3 for the text model.
+- It uses an updated processing logic for the images.
+- It removes the perceiver.
+
+The abstract from the paper is the following:
+
+*The field of vision-language models (VLMs), which take images and texts as inputs and output texts, is rapidly evolving and has yet to reach consensus on several key aspects of the development pipeline, including data, architecture, and training methods. This paper can be seen as a tutorial for building a VLM. We begin by providing a comprehensive overview of the current state-of-the-art approaches, highlighting the strengths and weaknesses of each, addressing the major challenges in the field, and suggesting promising research directions for underexplored areas. We then walk through the practical steps to build Idefics3-8B, a powerful VLM that significantly outperforms its predecessor Idefics2-8B, while being trained efficiently, exclusively on open datasets, and using a straightforward pipeline. These steps include the creation of Docmatix, a dataset for improving document understanding capabilities, which is 240 times larger than previously available datasets. We release the model along with the datasets created for its training.*
+
+## Usage tips
+
+Input images are processed either by upsampling (if resizing is enabled) or at their original resolution. The resizing behavior depends on two parameters: do_resize and size.
+
+If `do_resize` is set to `True`, the model resizes images so that the longest edge is 4*364 pixels by default.
+The default resizing behavior can be customized by passing a dictionary to the `size` parameter. For example, `{"longest_edge": 4 * 364}` is the default, but you can change it to a different value if needed.
+
+Here’s how to control resizing and set a custom size:
+```python
+image_processor = Idefics3ImageProcessor(do_resize=True, size={"longest_edge": 2 * 364}, max_image_size=364)
+```
+
+Additionally, the `max_image_size` parameter, which controls the size of each square patch the image is decomposed into, is set to 364 by default but can be adjusted as needed. After resizing (if applicable), the image processor decomposes the images into square patches based on the `max_image_size` parameter.
+
+This model was contributed by [amyeroberts](https://huggingface.co/amyeroberts) and [andimarafioti](https://huggingface.co/andito).
+
+
+## Idefics3Config
+
+[[autodoc]] Idefics3Config
+
+## Idefics3VisionConfig
+
+[[autodoc]] Idefics3VisionConfig
+
+## Idefics3VisionTransformer
+
+[[autodoc]] Idefics3VisionTransformer
+
+## Idefics3Model
+
+[[autodoc]] Idefics3Model
+ - forward
+
+## Idefics3ForConditionalGeneration
+
+[[autodoc]] Idefics3ForConditionalGeneration
+ - forward
+
+
+## Idefics3ImageProcessor
+[[autodoc]] Idefics3ImageProcessor
+ - preprocess
+
+
+## Idefics3Processor
+[[autodoc]] Idefics3Processor
+ - __call__
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/ijepa.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/ijepa.md
new file mode 100644
index 0000000000000000000000000000000000000000..cb2afd25e20bcaa3c04558a67abf54473598f832
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/ijepa.md
@@ -0,0 +1,92 @@
+
+
+# I-JEPA
+
+## Overview
+
+The I-JEPA model was proposed in [Image-based Joint-Embedding Predictive Architecture](https://arxiv.org/abs/2301.08243) by Mahmoud Assran, Quentin Duval, Ishan Misra, Piotr Bojanowski, Pascal Vincent, Michael Rabbat, Yann LeCun, Nicolas Ballas.
+I-JEPA is a self-supervised learning method that predicts the representations of one part of an image based on other parts of the same image. This approach focuses on learning semantic features without relying on pre-defined invariances from hand-crafted data transformations, which can bias specific tasks, or on filling in pixel-level details, which often leads to less meaningful representations.
+
+The abstract from the paper is the following:
+
+This paper demonstrates an approach for learning highly semantic image representations without relying on hand-crafted data-augmentations. We introduce the Image- based Joint-Embedding Predictive Architecture (I-JEPA), a non-generative approach for self-supervised learning from images. The idea behind I-JEPA is simple: from a single context block, predict the representations of various target blocks in the same image. A core design choice to guide I-JEPA towards producing semantic representations is the masking strategy; specifically, it is crucial to (a) sample tar- get blocks with sufficiently large scale (semantic), and to (b) use a sufficiently informative (spatially distributed) context block. Empirically, when combined with Vision Transform- ers, we find I-JEPA to be highly scalable. For instance, we train a ViT-Huge/14 on ImageNet using 16 A100 GPUs in under 72 hours to achieve strong downstream performance across a wide range of tasks, from linear classification to object counting and depth prediction.
+
+
+
+ I-JEPA architecture. Taken from the original paper.
+
+This model was contributed by [jmtzt](https://huggingface.co/jmtzt).
+The original code can be found [here](https://github.com/facebookresearch/ijepa).
+
+## How to use
+
+Here is how to use this model for image feature extraction:
+
+```python
+import requests
+import torch
+from PIL import Image
+from torch.nn.functional import cosine_similarity
+
+from transformers import AutoModel, AutoProcessor
+
+url_1 = "http://images.cocodataset.org/val2017/000000039769.jpg"
+url_2 = "http://images.cocodataset.org/val2017/000000219578.jpg"
+image_1 = Image.open(requests.get(url_1, stream=True).raw)
+image_2 = Image.open(requests.get(url_2, stream=True).raw)
+
+model_id = "facebook/ijepa_vith14_1k"
+processor = AutoProcessor.from_pretrained(model_id)
+model = AutoModel.from_pretrained(model_id)
+
+@torch.no_grad()
+def infer(image):
+ inputs = processor(image, return_tensors="pt")
+ outputs = model(**inputs)
+ return outputs.last_hidden_state.mean(dim=1)
+
+
+embed_1 = infer(image_1)
+embed_2 = infer(image_2)
+
+similarity = cosine_similarity(embed_1, embed_2)
+print(similarity)
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with I-JEPA.
+
+
+
+- [`IJepaForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+## IJepaConfig
+
+[[autodoc]] IJepaConfig
+
+## IJepaModel
+
+[[autodoc]] IJepaModel
+ - forward
+
+## IJepaForImageClassification
+
+[[autodoc]] IJepaForImageClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/imagegpt.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/imagegpt.md
new file mode 100644
index 0000000000000000000000000000000000000000..53a7ba3b34b7094189b15e47b6bdd823d81829a4
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/imagegpt.md
@@ -0,0 +1,115 @@
+
+
+# ImageGPT
+
+## Overview
+
+The ImageGPT model was proposed in [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt) by Mark
+Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever. ImageGPT (iGPT) is a GPT-2-like
+model trained to predict the next pixel value, allowing for both unconditional and conditional image generation.
+
+The abstract from the paper is the following:
+
+*Inspired by progress in unsupervised representation learning for natural language, we examine whether similar models
+can learn useful representations for images. We train a sequence Transformer to auto-regressively predict pixels,
+without incorporating knowledge of the 2D input structure. Despite training on low-resolution ImageNet without labels,
+we find that a GPT-2 scale model learns strong image representations as measured by linear probing, fine-tuning, and
+low-data classification. On CIFAR-10, we achieve 96.3% accuracy with a linear probe, outperforming a supervised Wide
+ResNet, and 99.0% accuracy with full fine-tuning, matching the top supervised pre-trained models. We are also
+competitive with self-supervised benchmarks on ImageNet when substituting pixels for a VQVAE encoding, achieving 69.0%
+top-1 accuracy on a linear probe of our features.*
+
+
+
+ Summary of the approach. Taken from the [original paper](https://cdn.openai.com/papers/Generative_Pretraining_from_Pixels_V2.pdf).
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr), based on [this issue](https://github.com/openai/image-gpt/issues/7). The original code can be found
+[here](https://github.com/openai/image-gpt).
+
+## Usage tips
+
+- ImageGPT is almost exactly the same as [GPT-2](gpt2), with the exception that a different activation
+ function is used (namely "quick gelu"), and the layer normalization layers don't mean center the inputs. ImageGPT
+ also doesn't have tied input- and output embeddings.
+- As the time- and memory requirements of the attention mechanism of Transformers scales quadratically in the sequence
+ length, the authors pre-trained ImageGPT on smaller input resolutions, such as 32x32 and 64x64. However, feeding a
+ sequence of 32x32x3=3072 tokens from 0..255 into a Transformer is still prohibitively large. Therefore, the authors
+ applied k-means clustering to the (R,G,B) pixel values with k=512. This way, we only have a 32*32 = 1024-long
+ sequence, but now of integers in the range 0..511. So we are shrinking the sequence length at the cost of a bigger
+ embedding matrix. In other words, the vocabulary size of ImageGPT is 512, + 1 for a special "start of sentence" (SOS)
+ token, used at the beginning of every sequence. One can use [`ImageGPTImageProcessor`] to prepare
+ images for the model.
+- Despite being pre-trained entirely unsupervised (i.e. without the use of any labels), ImageGPT produces fairly
+ performant image features useful for downstream tasks, such as image classification. The authors showed that the
+ features in the middle of the network are the most performant, and can be used as-is to train a linear model (such as
+ a sklearn logistic regression model for example). This is also referred to as "linear probing". Features can be
+ easily obtained by first forwarding the image through the model, then specifying `output_hidden_states=True`, and
+ then average-pool the hidden states at whatever layer you like.
+- Alternatively, one can further fine-tune the entire model on a downstream dataset, similar to BERT. For this, you can
+ use [`ImageGPTForImageClassification`].
+- ImageGPT comes in different sizes: there's ImageGPT-small, ImageGPT-medium and ImageGPT-large. The authors did also
+ train an XL variant, which they didn't release. The differences in size are summarized in the following table:
+
+| **Model variant** | **Depths** | **Hidden sizes** | **Decoder hidden size** | **Params (M)** | **ImageNet-1k Top 1** |
+|---|---|---|---|---|---|
+| MiT-b0 | [2, 2, 2, 2] | [32, 64, 160, 256] | 256 | 3.7 | 70.5 |
+| MiT-b1 | [2, 2, 2, 2] | [64, 128, 320, 512] | 256 | 14.0 | 78.7 |
+| MiT-b2 | [3, 4, 6, 3] | [64, 128, 320, 512] | 768 | 25.4 | 81.6 |
+| MiT-b3 | [3, 4, 18, 3] | [64, 128, 320, 512] | 768 | 45.2 | 83.1 |
+| MiT-b4 | [3, 8, 27, 3] | [64, 128, 320, 512] | 768 | 62.6 | 83.6 |
+| MiT-b5 | [3, 6, 40, 3] | [64, 128, 320, 512] | 768 | 82.0 | 83.8 |
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with ImageGPT.
+
+
+
+- Demo notebooks for ImageGPT can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/ImageGPT).
+- [`ImageGPTForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## ImageGPTConfig
+
+[[autodoc]] ImageGPTConfig
+
+## ImageGPTFeatureExtractor
+
+[[autodoc]] ImageGPTFeatureExtractor
+ - __call__
+
+## ImageGPTImageProcessor
+
+[[autodoc]] ImageGPTImageProcessor
+ - preprocess
+
+## ImageGPTModel
+
+[[autodoc]] ImageGPTModel
+ - forward
+
+## ImageGPTForCausalImageModeling
+
+[[autodoc]] ImageGPTForCausalImageModeling
+ - forward
+
+## ImageGPTForImageClassification
+
+[[autodoc]] ImageGPTForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/informer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/informer.md
new file mode 100644
index 0000000000000000000000000000000000000000..f866afbfcb8a9d6041d31fe45bd3bd76d7f2e6ff
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/informer.md
@@ -0,0 +1,50 @@
+
+
+# Informer
+
+## Overview
+
+The Informer model was proposed in [Informer: Beyond Efficient Transformer for Long Sequence Time-Series Forecasting](https://arxiv.org/abs/2012.07436) by Haoyi Zhou, Shanghang Zhang, Jieqi Peng, Shuai Zhang, Jianxin Li, Hui Xiong, and Wancai Zhang.
+
+This method introduces a Probabilistic Attention mechanism to select the "active" queries rather than the "lazy" queries and provides a sparse Transformer thus mitigating the quadratic compute and memory requirements of vanilla attention.
+
+The abstract from the paper is the following:
+
+*Many real-world applications require the prediction of long sequence time-series, such as electricity consumption planning. Long sequence time-series forecasting (LSTF) demands a high prediction capacity of the model, which is the ability to capture precise long-range dependency coupling between output and input efficiently. Recent studies have shown the potential of Transformer to increase the prediction capacity. However, there are several severe issues with Transformer that prevent it from being directly applicable to LSTF, including quadratic time complexity, high memory usage, and inherent limitation of the encoder-decoder architecture. To address these issues, we design an efficient transformer-based model for LSTF, named Informer, with three distinctive characteristics: (i) a ProbSparse self-attention mechanism, which achieves O(L logL) in time complexity and memory usage, and has comparable performance on sequences' dependency alignment. (ii) the self-attention distilling highlights dominating attention by halving cascading layer input, and efficiently handles extreme long input sequences. (iii) the generative style decoder, while conceptually simple, predicts the long time-series sequences at one forward operation rather than a step-by-step way, which drastically improves the inference speed of long-sequence predictions. Extensive experiments on four large-scale datasets demonstrate that Informer significantly outperforms existing methods and provides a new solution to the LSTF problem.*
+
+This model was contributed by [elisim](https://huggingface.co/elisim) and [kashif](https://huggingface.co/kashif).
+The original code can be found [here](https://github.com/zhouhaoyi/Informer2020).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- Check out the Informer blog-post in HuggingFace blog: [Multivariate Probabilistic Time Series Forecasting with Informer](https://huggingface.co/blog/informer)
+
+## InformerConfig
+
+[[autodoc]] InformerConfig
+
+## InformerModel
+
+[[autodoc]] InformerModel
+ - forward
+
+## InformerForPrediction
+
+[[autodoc]] InformerForPrediction
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/instructblip.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/instructblip.md
new file mode 100644
index 0000000000000000000000000000000000000000..904a96bc786f075d32ab19cf85afaf1e4e6727f4
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/instructblip.md
@@ -0,0 +1,72 @@
+
+
+# InstructBLIP
+
+## Overview
+
+The InstructBLIP model was proposed in [InstructBLIP: Towards General-purpose Vision-Language Models with Instruction Tuning](https://arxiv.org/abs/2305.06500) by Wenliang Dai, Junnan Li, Dongxu Li, Anthony Meng Huat Tiong, Junqi Zhao, Weisheng Wang, Boyang Li, Pascale Fung, Steven Hoi.
+InstructBLIP leverages the [BLIP-2](blip2) architecture for visual instruction tuning.
+
+The abstract from the paper is the following:
+
+*General-purpose language models that can solve various language-domain tasks have emerged driven by the pre-training and instruction-tuning pipeline. However, building general-purpose vision-language models is challenging due to the increased task discrepancy introduced by the additional visual input. Although vision-language pre-training has been widely studied, vision-language instruction tuning remains relatively less explored. In this paper, we conduct a systematic and comprehensive study on vision-language instruction tuning based on the pre-trained BLIP-2 models. We gather a wide variety of 26 publicly available datasets, transform them into instruction tuning format and categorize them into two clusters for held-in instruction tuning and held-out zero-shot evaluation. Additionally, we introduce instruction-aware visual feature extraction, a crucial method that enables the model to extract informative features tailored to the given instruction. The resulting InstructBLIP models achieve state-of-the-art zero-shot performance across all 13 held-out datasets, substantially outperforming BLIP-2 and the larger Flamingo. Our models also lead to state-of-the-art performance when finetuned on individual downstream tasks (e.g., 90.7% accuracy on ScienceQA IMG). Furthermore, we qualitatively demonstrate the advantages of InstructBLIP over concurrent multimodal models.*
+
+
+
+ InstructBLIP architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/salesforce/LAVIS/tree/main/projects/instructblip).
+
+## Usage tips
+
+InstructBLIP uses the same architecture as [BLIP-2](blip2) with a tiny but important difference: it also feeds the text prompt (instruction) to the Q-Former.
+
+> [!NOTE]
+> BLIP models after release v4.46 will raise warnings about adding `processor.num_query_tokens = {{num_query_tokens}}` and expand model embeddings layer to add special `` token. It is strongly recommended to add the attributes to the processor if you own the model checkpoint, or open a PR if it is not owned by you. Adding these attributes means that BLIP will add the number of query tokens required per image and expand the text with as many `` placeholders as there will be query tokens. Usually it is around 500 tokens per image, so make sure that the text is not truncated as otherwise there wil be failure when merging the embeddings.
+The attributes can be obtained from model config, as `model.config.num_query_tokens` and model embeddings expansion can be done by following [this link](https://gist.github.com/zucchini-nlp/e9f20b054fa322f84ac9311d9ab67042).
+
+## InstructBlipConfig
+
+[[autodoc]] InstructBlipConfig
+ - from_vision_qformer_text_configs
+
+## InstructBlipVisionConfig
+
+[[autodoc]] InstructBlipVisionConfig
+
+## InstructBlipQFormerConfig
+
+[[autodoc]] InstructBlipQFormerConfig
+
+## InstructBlipProcessor
+
+[[autodoc]] InstructBlipProcessor
+
+
+## InstructBlipVisionModel
+
+[[autodoc]] InstructBlipVisionModel
+ - forward
+
+## InstructBlipQFormerModel
+
+[[autodoc]] InstructBlipQFormerModel
+ - forward
+
+## InstructBlipForConditionalGeneration
+
+[[autodoc]] InstructBlipForConditionalGeneration
+ - forward
+ - generate
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/instructblipvideo.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/instructblipvideo.md
new file mode 100644
index 0000000000000000000000000000000000000000..8b2207ce176566afa58f9f3074ec6ce982352d2a
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/instructblipvideo.md
@@ -0,0 +1,78 @@
+
+
+# InstructBlipVideo
+
+## Overview
+
+## Overview
+
+The InstructBLIPVideo is an extension of the models proposed in [InstructBLIP: Towards General-purpose Vision-Language Models with Instruction Tuning](https://arxiv.org/abs/2305.06500) by Wenliang Dai, Junnan Li, Dongxu Li, Anthony Meng Huat Tiong, Junqi Zhao, Weisheng Wang, Boyang Li, Pascale Fung, Steven Hoi.
+InstructBLIPVideo uses the same architecture as [InstructBLIP](instructblip) and works with the same checkpoints as [InstructBLIP](instructblip). The only difference is the ability to process videos.
+
+The abstract from the paper is the following:
+
+*General-purpose language models that can solve various language-domain tasks have emerged driven by the pre-training and instruction-tuning pipeline. However, building general-purpose vision-language models is challenging due to the increased task discrepancy introduced by the additional visual input. Although vision-language pre-training has been widely studied, vision-language instruction tuning remains relatively less explored. In this paper, we conduct a systematic and comprehensive study on vision-language instruction tuning based on the pre-trained BLIP-2 models. We gather a wide variety of 26 publicly available datasets, transform them into instruction tuning format and categorize them into two clusters for held-in instruction tuning and held-out zero-shot evaluation. Additionally, we introduce instruction-aware visual feature extraction, a crucial method that enables the model to extract informative features tailored to the given instruction. The resulting InstructBLIP models achieve state-of-the-art zero-shot performance across all 13 held-out datasets, substantially outperforming BLIP-2 and the larger Flamingo. Our models also lead to state-of-the-art performance when finetuned on individual downstream tasks (e.g., 90.7% accuracy on ScienceQA IMG). Furthermore, we qualitatively demonstrate the advantages of InstructBLIP over concurrent multimodal models.*
+
+
+
+ InstructBLIPVideo architecture. Taken from the original paper.
+
+This model was contributed by [RaushanTurganbay](https://huggingface.co/RaushanTurganbay).
+The original code can be found [here](https://github.com/salesforce/LAVIS/tree/main/projects/instructblip).
+
+## Usage tips
+
+- The model was trained by sampling 4 frames per video, so it's recommended to sample 4 frames
+
+> [!NOTE]
+> BLIP models after release v4.46 will raise warnings about adding `processor.num_query_tokens = {{num_query_tokens}}` and expand model embeddings layer to add special `` token. It is strongly recommended to add the attributes to the processor if you own the model checkpoint, or open a PR if it is not owned by you. Adding these attributes means that BLIP will add the number of query tokens required per image and expand the text with as many `` placeholders as there will be query tokens. Usually it is around 500 tokens per image, so make sure that the text is not truncated as otherwise there wil be failure when merging the embeddings.
+The attributes can be obtained from model config, as `model.config.num_query_tokens` and model embeddings expansion can be done by following [this link](https://gist.github.com/zucchini-nlp/e9f20b054fa322f84ac9311d9ab67042).
+
+## InstructBlipVideoConfig
+
+[[autodoc]] InstructBlipVideoConfig
+ - from_vision_qformer_text_configs
+
+## InstructBlipVideoVisionConfig
+
+[[autodoc]] InstructBlipVideoVisionConfig
+
+## InstructBlipVideoQFormerConfig
+
+[[autodoc]] InstructBlipVideoQFormerConfig
+
+## InstructBlipVideoProcessor
+
+[[autodoc]] InstructBlipVideoProcessor
+
+## InstructBlipVideoImageProcessor
+
+[[autodoc]] InstructBlipVideoImageProcessor
+ - preprocess
+
+## InstructBlipVideoVisionModel
+
+[[autodoc]] InstructBlipVideoVisionModel
+ - forward
+
+## InstructBlipVideoQFormerModel
+
+[[autodoc]] InstructBlipVideoQFormerModel
+ - forward
+
+## InstructBlipVideoForConditionalGeneration
+
+[[autodoc]] InstructBlipVideoForConditionalGeneration
+ - forward
+ - generate
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/jamba.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/jamba.md
new file mode 100644
index 0000000000000000000000000000000000000000..c3f66c1825f39450647c838e2f1d1d89478ee147
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/jamba.md
@@ -0,0 +1,122 @@
+
+
+# Jamba
+
+## Overview
+
+Jamba is a state-of-the-art, hybrid SSM-Transformer LLM. It is the first production-scale Mamba implementation, which opens up interesting research and application opportunities. While this initial experimentation shows encouraging gains, we expect these to be further enhanced with future optimizations and explorations.
+
+For full details of this model please read the [release blog post](https://www.ai21.com/blog/announcing-jamba).
+
+### Model Details
+
+Jamba is a pretrained, mixture-of-experts (MoE) generative text model, with 12B active parameters and an overall of 52B parameters across all experts. It supports a 256K context length, and can fit up to 140K tokens on a single 80GB GPU.
+
+As depicted in the diagram below, Jamba's architecture features a blocks-and-layers approach that allows Jamba to successfully integrate Transformer and Mamba architectures altogether. Each Jamba block contains either an attention or a Mamba layer, followed by a multi-layer perceptron (MLP), producing an overall ratio of one Transformer layer out of every eight total layers.
+
+
+
+## Usage
+
+### Prerequisites
+
+Jamba requires you use `transformers` version 4.39.0 or higher:
+```bash
+pip install transformers>=4.39.0
+```
+
+In order to run optimized Mamba implementations, you first need to install `mamba-ssm` and `causal-conv1d`:
+```bash
+pip install mamba-ssm causal-conv1d>=1.2.0
+```
+You also have to have the model on a CUDA device.
+
+You can run the model not using the optimized Mamba kernels, but it is **not** recommended as it will result in significantly lower latencies. In order to do that, you'll need to specify `use_mamba_kernels=False` when loading the model.
+
+### Run the model
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained("ai21labs/Jamba-v0.1")
+tokenizer = AutoTokenizer.from_pretrained("ai21labs/Jamba-v0.1")
+
+input_ids = tokenizer("In the recent Super Bowl LVIII,", return_tensors='pt').to(model.device)["input_ids"]
+
+outputs = model.generate(input_ids, max_new_tokens=216)
+
+print(tokenizer.batch_decode(outputs))
+# ["<|startoftext|>In the recent Super Bowl LVIII, the Kansas City Chiefs emerged victorious, defeating the San Francisco 49ers in a thrilling overtime showdown. The game was a nail-biter, with both teams showcasing their skills and determination.\n\nThe Chiefs, led by their star quarterback Patrick Mahomes, displayed their offensive prowess, while the 49ers, led by their strong defense, put up a tough fight. The game went into overtime, with the Chiefs ultimately securing the win with a touchdown.\n\nThe victory marked the Chiefs' second Super Bowl win in four years, solidifying their status as one of the top teams in the NFL. The game was a testament to the skill and talent of both teams, and a thrilling end to the NFL season.\n\nThe Super Bowl is not just about the game itself, but also about the halftime show and the commercials. This year's halftime show featured a star-studded lineup, including Usher, Alicia Keys, and Lil Jon. The show was a spectacle of music and dance, with the performers delivering an energetic and entertaining performance.\n"]
+```
+
+
+Loading the model in half precision
+
+The published checkpoint is saved in BF16. In order to load it into RAM in BF16/FP16, you need to specify `torch_dtype`:
+
+```python
+from transformers import AutoModelForCausalLM
+import torch
+model = AutoModelForCausalLM.from_pretrained("ai21labs/Jamba-v0.1", torch_dtype=torch.bfloat16)
+# you can also use torch_dtype=torch.float16
+```
+
+When using half precision, you can enable the [FlashAttention2](https://github.com/Dao-AILab/flash-attention) implementation of the Attention blocks. In order to use it, you also need the model on a CUDA device. Since in this precision the model is to big to fit on a single 80GB GPU, you'll also need to parallelize it using [accelerate](https://huggingface.co/docs/accelerate/index):
+```python
+from transformers import AutoModelForCausalLM
+import torch
+model = AutoModelForCausalLM.from_pretrained("ai21labs/Jamba-v0.1",
+ torch_dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+ device_map="auto")
+```
+
+
+Load the model in 8-bit
+
+**Using 8-bit precision, it is possible to fit up to 140K sequence lengths on a single 80GB GPU.** You can easily quantize the model to 8-bit using [bitsandbytes](https://huggingface.co/docs/bitsandbytes/index). In order to not degrade model quality, we recommend to exclude the Mamba blocks from the quantization:
+
+```python
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+quantization_config = BitsAndBytesConfig(load_in_8bit=True, llm_int8_skip_modules=["mamba"])
+model = AutoModelForCausalLM.from_pretrained(
+ "ai21labs/Jamba-v0.1", torch_dtype=torch.bfloat16, attn_implementation="flash_attention_2", quantization_config=quantization_config
+)
+```
+
+
+## JambaConfig
+
+[[autodoc]] JambaConfig
+
+
+## JambaModel
+
+[[autodoc]] JambaModel
+ - forward
+
+
+## JambaForCausalLM
+
+[[autodoc]] JambaForCausalLM
+ - forward
+
+
+## JambaForSequenceClassification
+
+[[autodoc]] transformers.JambaForSequenceClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/jetmoe.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/jetmoe.md
new file mode 100644
index 0000000000000000000000000000000000000000..87f99c6f998875f1e0a2310d3dce1719219b46ea
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/jetmoe.md
@@ -0,0 +1,49 @@
+
+
+# JetMoe
+
+## Overview
+
+**JetMoe-8B** is an 8B Mixture-of-Experts (MoE) language model developed by [Yikang Shen](https://scholar.google.com.hk/citations?user=qff5rRYAAAAJ) and [MyShell](https://myshell.ai/).
+JetMoe project aims to provide a LLaMA2-level performance and efficient language model with a limited budget.
+To achieve this goal, JetMoe uses a sparsely activated architecture inspired by the [ModuleFormer](https://arxiv.org/abs/2306.04640).
+Each JetMoe block consists of two MoE layers: Mixture of Attention Heads and Mixture of MLP Experts.
+Given the input tokens, it activates a subset of its experts to process them.
+This sparse activation schema enables JetMoe to achieve much better training throughput than similar size dense models.
+The training throughput of JetMoe-8B is around 100B tokens per day on a cluster of 96 H100 GPUs with a straightforward 3-way pipeline parallelism strategy.
+
+This model was contributed by [Yikang Shen](https://huggingface.co/YikangS).
+
+
+## JetMoeConfig
+
+[[autodoc]] JetMoeConfig
+
+## JetMoeModel
+
+[[autodoc]] JetMoeModel
+ - forward
+
+## JetMoeForCausalLM
+
+[[autodoc]] JetMoeForCausalLM
+ - forward
+
+## JetMoeForSequenceClassification
+
+[[autodoc]] JetMoeForSequenceClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/jukebox.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/jukebox.md
new file mode 100644
index 0000000000000000000000000000000000000000..12f273b71e972cba145863d803d4fef7d9985a6f
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/jukebox.md
@@ -0,0 +1,93 @@
+
+# Jukebox
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The Jukebox model was proposed in [Jukebox: A generative model for music](https://arxiv.org/pdf/2005.00341.pdf)
+by Prafulla Dhariwal, Heewoo Jun, Christine Payne, Jong Wook Kim, Alec Radford,
+Ilya Sutskever. It introduces a generative music model which can produce minute long samples that can be conditioned on
+an artist, genres and lyrics.
+
+The abstract from the paper is the following:
+
+*We introduce Jukebox, a model that generates music with singing in the raw audio domain. We tackle the long context of raw audio using a multiscale VQ-VAE to compress it to discrete codes, and modeling those using autoregressive Transformers. We show that the combined model at scale can generate high-fidelity and diverse songs with coherence up to multiple minutes. We can condition on artist and genre to steer the musical and vocal style, and on unaligned lyrics to make the singing more controllable. We are releasing thousands of non cherry-picked samples, along with model weights and code.*
+
+As shown on the following figure, Jukebox is made of 3 `priors` which are decoder only models. They follow the architecture described in [Generating Long Sequences with Sparse Transformers](https://arxiv.org/abs/1904.10509), modified to support longer context length.
+First, a autoencoder is used to encode the text lyrics. Next, the first (also called `top_prior`) prior attends to the last hidden states extracted from the lyrics encoder. The priors are linked to the previous priors respectively via an `AudioConditioner` module. The`AudioConditioner` upsamples the outputs of the previous prior to raw tokens at a certain audio frame per second resolution.
+The metadata such as *artist, genre and timing* are passed to each prior, in the form of a start token and positional embedding for the timing data. The hidden states are mapped to the closest codebook vector from the VQVAE in order to convert them to raw audio.
+
+
+
+This model was contributed by [Arthur Zucker](https://huggingface.co/ArthurZ).
+The original code can be found [here](https://github.com/openai/jukebox).
+
+## Usage tips
+
+- This model only supports inference. This is for a few reasons, mostly because it requires a crazy amount of memory to train. Feel free to open a PR and add what's missing to have a full integration with the hugging face trainer!
+- This model is very slow, and takes 8h to generate a minute long audio using the 5b top prior on a V100 GPU. In order automaticallay handle the device on which the model should execute, use `accelerate`.
+- Contrary to the paper, the order of the priors goes from `0` to `1` as it felt more intuitive : we sample starting from `0`.
+- Primed sampling (conditioning the sampling on raw audio) requires more memory than ancestral sampling and should be used with `fp16` set to `True`.
+
+This model was contributed by [Arthur Zucker](https://huggingface.co/ArthurZ).
+The original code can be found [here](https://github.com/openai/jukebox).
+
+## JukeboxConfig
+
+[[autodoc]] JukeboxConfig
+
+## JukeboxPriorConfig
+
+[[autodoc]] JukeboxPriorConfig
+
+## JukeboxVQVAEConfig
+
+[[autodoc]] JukeboxVQVAEConfig
+
+## JukeboxTokenizer
+
+[[autodoc]] JukeboxTokenizer
+ - save_vocabulary
+
+## JukeboxModel
+
+[[autodoc]] JukeboxModel
+ - ancestral_sample
+ - primed_sample
+ - continue_sample
+ - upsample
+ - _sample
+
+## JukeboxPrior
+
+[[autodoc]] JukeboxPrior
+ - sample
+ - forward
+
+## JukeboxVQVAE
+
+[[autodoc]] JukeboxVQVAE
+ - forward
+ - encode
+ - decode
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/kosmos-2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/kosmos-2.md
new file mode 100644
index 0000000000000000000000000000000000000000..f799751cce84966609c74df0d7101869e56f2b5e
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/kosmos-2.md
@@ -0,0 +1,98 @@
+
+
+# KOSMOS-2
+
+## Overview
+
+The KOSMOS-2 model was proposed in [Kosmos-2: Grounding Multimodal Large Language Models to the World](https://arxiv.org/abs/2306.14824) by Zhiliang Peng, Wenhui Wang, Li Dong, Yaru Hao, Shaohan Huang, Shuming Ma, Furu Wei.
+
+KOSMOS-2 is a Transformer-based causal language model and is trained using the next-word prediction task on a web-scale
+dataset of grounded image-text pairs [GRIT](https://huggingface.co/datasets/zzliang/GRIT). The spatial coordinates of
+the bounding boxes in the dataset are converted to a sequence of location tokens, which are appended to their respective
+entity text spans (for example, `a snowman` followed by ``). The data format is
+similar to “hyperlinks” that connect the object regions in an image to their text span in the corresponding caption.
+
+The abstract from the paper is the following:
+
+*We introduce Kosmos-2, a Multimodal Large Language Model (MLLM), enabling new capabilities of perceiving object descriptions (e.g., bounding boxes) and grounding text to the visual world. Specifically, we represent refer expressions as links in Markdown, i.e., ``[text span](bounding boxes)'', where object descriptions are sequences of location tokens. Together with multimodal corpora, we construct large-scale data of grounded image-text pairs (called GrIT) to train the model. In addition to the existing capabilities of MLLMs (e.g., perceiving general modalities, following instructions, and performing in-context learning), Kosmos-2 integrates the grounding capability into downstream applications. We evaluate Kosmos-2 on a wide range of tasks, including (i) multimodal grounding, such as referring expression comprehension, and phrase grounding, (ii) multimodal referring, such as referring expression generation, (iii) perception-language tasks, and (iv) language understanding and generation. This work lays out the foundation for the development of Embodiment AI and sheds light on the big convergence of language, multimodal perception, action, and world modeling, which is a key step toward artificial general intelligence. Code and pretrained models are available at https://aka.ms/kosmos-2.*
+
+
+
+ Overview of tasks that KOSMOS-2 can handle. Taken from the original paper.
+
+## Example
+
+```python
+>>> from PIL import Image
+>>> import requests
+>>> from transformers import AutoProcessor, Kosmos2ForConditionalGeneration
+
+>>> model = Kosmos2ForConditionalGeneration.from_pretrained("microsoft/kosmos-2-patch14-224")
+>>> processor = AutoProcessor.from_pretrained("microsoft/kosmos-2-patch14-224")
+
+>>> url = "https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/snowman.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> prompt = " An image of"
+
+>>> inputs = processor(text=prompt, images=image, return_tensors="pt")
+
+>>> generated_ids = model.generate(
+... pixel_values=inputs["pixel_values"],
+... input_ids=inputs["input_ids"],
+... attention_mask=inputs["attention_mask"],
+... image_embeds=None,
+... image_embeds_position_mask=inputs["image_embeds_position_mask"],
+... use_cache=True,
+... max_new_tokens=64,
+... )
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+>>> processed_text = processor.post_process_generation(generated_text, cleanup_and_extract=False)
+>>> processed_text
+' An image of a snowman warming himself by a fire.'
+
+>>> caption, entities = processor.post_process_generation(generated_text)
+>>> caption
+'An image of a snowman warming himself by a fire.'
+
+>>> entities
+[('a snowman', (12, 21), [(0.390625, 0.046875, 0.984375, 0.828125)]), ('a fire', (41, 47), [(0.171875, 0.015625, 0.484375, 0.890625)])]
+```
+
+This model was contributed by [Yih-Dar SHIEH](https://huggingface.co/ydshieh). The original code can be found [here](https://github.com/microsoft/unilm/tree/master/kosmos-2).
+
+## Kosmos2Config
+
+[[autodoc]] Kosmos2Config
+
+## Kosmos2ImageProcessor
+
+## Kosmos2Processor
+
+[[autodoc]] Kosmos2Processor
+ - __call__
+
+## Kosmos2Model
+
+[[autodoc]] Kosmos2Model
+ - forward
+
+## Kosmos2ForConditionalGeneration
+
+[[autodoc]] Kosmos2ForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/layoutlm.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/layoutlm.md
new file mode 100644
index 0000000000000000000000000000000000000000..34b429fb73763ad52dab75d08fcd1874c37dc7a6
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/layoutlm.md
@@ -0,0 +1,175 @@
+
+
+# LayoutLM
+
+
+
+## Overview
+
+The LayoutLM model was proposed in the paper [LayoutLM: Pre-training of Text and Layout for Document Image
+Understanding](https://arxiv.org/abs/1912.13318) by Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, and
+Ming Zhou. It's a simple but effective pretraining method of text and layout for document image understanding and
+information extraction tasks, such as form understanding and receipt understanding. It obtains state-of-the-art results
+on several downstream tasks:
+
+- form understanding: the [FUNSD](https://guillaumejaume.github.io/FUNSD/) dataset (a collection of 199 annotated
+ forms comprising more than 30,000 words).
+- receipt understanding: the [SROIE](https://rrc.cvc.uab.es/?ch=13) dataset (a collection of 626 receipts for
+ training and 347 receipts for testing).
+- document image classification: the [RVL-CDIP](https://www.cs.cmu.edu/~aharley/rvl-cdip/) dataset (a collection of
+ 400,000 images belonging to one of 16 classes).
+
+The abstract from the paper is the following:
+
+*Pre-training techniques have been verified successfully in a variety of NLP tasks in recent years. Despite the
+widespread use of pretraining models for NLP applications, they almost exclusively focus on text-level manipulation,
+while neglecting layout and style information that is vital for document image understanding. In this paper, we propose
+the LayoutLM to jointly model interactions between text and layout information across scanned document images, which is
+beneficial for a great number of real-world document image understanding tasks such as information extraction from
+scanned documents. Furthermore, we also leverage image features to incorporate words' visual information into LayoutLM.
+To the best of our knowledge, this is the first time that text and layout are jointly learned in a single framework for
+document-level pretraining. It achieves new state-of-the-art results in several downstream tasks, including form
+understanding (from 70.72 to 79.27), receipt understanding (from 94.02 to 95.24) and document image classification
+(from 93.07 to 94.42).*
+
+## Usage tips
+
+- In addition to *input_ids*, [`~transformers.LayoutLMModel.forward`] also expects the input `bbox`, which are
+ the bounding boxes (i.e. 2D-positions) of the input tokens. These can be obtained using an external OCR engine such
+ as Google's [Tesseract](https://github.com/tesseract-ocr/tesseract) (there's a [Python wrapper](https://pypi.org/project/pytesseract/) available). Each bounding box should be in (x0, y0, x1, y1) format, where
+ (x0, y0) corresponds to the position of the upper left corner in the bounding box, and (x1, y1) represents the
+ position of the lower right corner. Note that one first needs to normalize the bounding boxes to be on a 0-1000
+ scale. To normalize, you can use the following function:
+
+```python
+def normalize_bbox(bbox, width, height):
+ return [
+ int(1000 * (bbox[0] / width)),
+ int(1000 * (bbox[1] / height)),
+ int(1000 * (bbox[2] / width)),
+ int(1000 * (bbox[3] / height)),
+ ]
+```
+
+Here, `width` and `height` correspond to the width and height of the original document in which the token
+occurs. Those can be obtained using the Python Image Library (PIL) library for example, as follows:
+
+```python
+from PIL import Image
+
+# Document can be a png, jpg, etc. PDFs must be converted to images.
+image = Image.open(name_of_your_document).convert("RGB")
+
+width, height = image.size
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LayoutLM. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+
+- A blog post on [fine-tuning
+ LayoutLM for document-understanding using Keras & Hugging Face
+ Transformers](https://www.philschmid.de/fine-tuning-layoutlm-keras).
+
+- A blog post on how to [fine-tune LayoutLM for document-understanding using only Hugging Face Transformers](https://www.philschmid.de/fine-tuning-layoutlm).
+
+- A notebook on how to [fine-tune LayoutLM on the FUNSD dataset with image embeddings](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Add_image_embeddings_to_LayoutLM.ipynb).
+
+- See also: [Document question answering task guide](../tasks/document_question_answering)
+
+
+
+- A notebook on how to [fine-tune LayoutLM for sequence classification on the RVL-CDIP dataset](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForSequenceClassification_on_RVL_CDIP.ipynb).
+- [Text classification task guide](../tasks/sequence_classification)
+
+
+
+- A notebook on how to [ fine-tune LayoutLM for token classification on the FUNSD dataset](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForTokenClassification_on_FUNSD.ipynb).
+- [Token classification task guide](../tasks/token_classification)
+
+**Other resources**
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+
+🚀 Deploy
+
+- A blog post on how to [Deploy LayoutLM with Hugging Face Inference Endpoints](https://www.philschmid.de/inference-endpoints-layoutlm).
+
+## LayoutLMConfig
+
+[[autodoc]] LayoutLMConfig
+
+## LayoutLMTokenizer
+
+[[autodoc]] LayoutLMTokenizer
+
+## LayoutLMTokenizerFast
+
+[[autodoc]] LayoutLMTokenizerFast
+
+
+
+
+## LayoutLMModel
+
+[[autodoc]] LayoutLMModel
+
+## LayoutLMForMaskedLM
+
+[[autodoc]] LayoutLMForMaskedLM
+
+## LayoutLMForSequenceClassification
+
+[[autodoc]] LayoutLMForSequenceClassification
+
+## LayoutLMForTokenClassification
+
+[[autodoc]] LayoutLMForTokenClassification
+
+## LayoutLMForQuestionAnswering
+
+[[autodoc]] LayoutLMForQuestionAnswering
+
+
+
+
+## TFLayoutLMModel
+
+[[autodoc]] TFLayoutLMModel
+
+## TFLayoutLMForMaskedLM
+
+[[autodoc]] TFLayoutLMForMaskedLM
+
+## TFLayoutLMForSequenceClassification
+
+[[autodoc]] TFLayoutLMForSequenceClassification
+
+## TFLayoutLMForTokenClassification
+
+[[autodoc]] TFLayoutLMForTokenClassification
+
+## TFLayoutLMForQuestionAnswering
+
+[[autodoc]] TFLayoutLMForQuestionAnswering
+
+
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/layoutlmv2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/layoutlmv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..0769322e9ad54c8904ed286ca1cdefe10e92439c
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/layoutlmv2.md
@@ -0,0 +1,340 @@
+
+
+# LayoutLMV2
+
+## Overview
+
+The LayoutLMV2 model was proposed in [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://arxiv.org/abs/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu,
+Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou. LayoutLMV2 improves [LayoutLM](layoutlm) to obtain
+state-of-the-art results across several document image understanding benchmarks:
+
+- information extraction from scanned documents: the [FUNSD](https://guillaumejaume.github.io/FUNSD/) dataset (a
+ collection of 199 annotated forms comprising more than 30,000 words), the [CORD](https://github.com/clovaai/cord)
+ dataset (a collection of 800 receipts for training, 100 for validation and 100 for testing), the [SROIE](https://rrc.cvc.uab.es/?ch=13) dataset (a collection of 626 receipts for training and 347 receipts for testing)
+ and the [Kleister-NDA](https://github.com/applicaai/kleister-nda) dataset (a collection of non-disclosure
+ agreements from the EDGAR database, including 254 documents for training, 83 documents for validation, and 203
+ documents for testing).
+- document image classification: the [RVL-CDIP](https://www.cs.cmu.edu/~aharley/rvl-cdip/) dataset (a collection of
+ 400,000 images belonging to one of 16 classes).
+- document visual question answering: the [DocVQA](https://arxiv.org/abs/2007.00398) dataset (a collection of 50,000
+ questions defined on 12,000+ document images).
+
+The abstract from the paper is the following:
+
+*Pre-training of text and layout has proved effective in a variety of visually-rich document understanding tasks due to
+its effective model architecture and the advantage of large-scale unlabeled scanned/digital-born documents. In this
+paper, we present LayoutLMv2 by pre-training text, layout and image in a multi-modal framework, where new model
+architectures and pre-training tasks are leveraged. Specifically, LayoutLMv2 not only uses the existing masked
+visual-language modeling task but also the new text-image alignment and text-image matching tasks in the pre-training
+stage, where cross-modality interaction is better learned. Meanwhile, it also integrates a spatial-aware self-attention
+mechanism into the Transformer architecture, so that the model can fully understand the relative positional
+relationship among different text blocks. Experiment results show that LayoutLMv2 outperforms strong baselines and
+achieves new state-of-the-art results on a wide variety of downstream visually-rich document understanding tasks,
+including FUNSD (0.7895 -> 0.8420), CORD (0.9493 -> 0.9601), SROIE (0.9524 -> 0.9781), Kleister-NDA (0.834 -> 0.852),
+RVL-CDIP (0.9443 -> 0.9564), and DocVQA (0.7295 -> 0.8672). The pre-trained LayoutLMv2 model is publicly available at
+this https URL.*
+
+LayoutLMv2 depends on `detectron2`, `torchvision` and `tesseract`. Run the
+following to install them:
+```bash
+python -m pip install 'git+https://github.com/facebookresearch/detectron2.git'
+python -m pip install torchvision tesseract
+```
+(If you are developing for LayoutLMv2, note that passing the doctests also requires the installation of these packages.)
+
+## Usage tips
+
+- The main difference between LayoutLMv1 and LayoutLMv2 is that the latter incorporates visual embeddings during
+ pre-training (while LayoutLMv1 only adds visual embeddings during fine-tuning).
+- LayoutLMv2 adds both a relative 1D attention bias as well as a spatial 2D attention bias to the attention scores in
+ the self-attention layers. Details can be found on page 5 of the [paper](https://arxiv.org/abs/2012.14740).
+- Demo notebooks on how to use the LayoutLMv2 model on RVL-CDIP, FUNSD, DocVQA, CORD can be found [here](https://github.com/NielsRogge/Transformers-Tutorials).
+- LayoutLMv2 uses Facebook AI's [Detectron2](https://github.com/facebookresearch/detectron2/) package for its visual
+ backbone. See [this link](https://detectron2.readthedocs.io/en/latest/tutorials/install.html) for installation
+ instructions.
+- In addition to `input_ids`, [`~LayoutLMv2Model.forward`] expects 2 additional inputs, namely
+ `image` and `bbox`. The `image` input corresponds to the original document image in which the text
+ tokens occur. The model expects each document image to be of size 224x224. This means that if you have a batch of
+ document images, `image` should be a tensor of shape (batch_size, 3, 224, 224). This can be either a
+ `torch.Tensor` or a `Detectron2.structures.ImageList`. You don't need to normalize the channels, as this is
+ done by the model. Important to note is that the visual backbone expects BGR channels instead of RGB, as all models
+ in Detectron2 are pre-trained using the BGR format. The `bbox` input are the bounding boxes (i.e. 2D-positions)
+ of the input text tokens. This is identical to [`LayoutLMModel`]. These can be obtained using an
+ external OCR engine such as Google's [Tesseract](https://github.com/tesseract-ocr/tesseract) (there's a [Python
+ wrapper](https://pypi.org/project/pytesseract/) available). Each bounding box should be in (x0, y0, x1, y1)
+ format, where (x0, y0) corresponds to the position of the upper left corner in the bounding box, and (x1, y1)
+ represents the position of the lower right corner. Note that one first needs to normalize the bounding boxes to be on
+ a 0-1000 scale. To normalize, you can use the following function:
+
+```python
+def normalize_bbox(bbox, width, height):
+ return [
+ int(1000 * (bbox[0] / width)),
+ int(1000 * (bbox[1] / height)),
+ int(1000 * (bbox[2] / width)),
+ int(1000 * (bbox[3] / height)),
+ ]
+```
+
+Here, `width` and `height` correspond to the width and height of the original document in which the token
+occurs (before resizing the image). Those can be obtained using the Python Image Library (PIL) library for example, as
+follows:
+
+```python
+from PIL import Image
+
+image = Image.open(
+ "name_of_your_document - can be a png, jpg, etc. of your documents (PDFs must be converted to images)."
+)
+
+width, height = image.size
+```
+
+However, this model includes a brand new [`~transformers.LayoutLMv2Processor`] which can be used to directly
+prepare data for the model (including applying OCR under the hood). More information can be found in the "Usage"
+section below.
+
+- Internally, [`~transformers.LayoutLMv2Model`] will send the `image` input through its visual backbone to
+ obtain a lower-resolution feature map, whose shape is equal to the `image_feature_pool_shape` attribute of
+ [`~transformers.LayoutLMv2Config`]. This feature map is then flattened to obtain a sequence of image tokens. As
+ the size of the feature map is 7x7 by default, one obtains 49 image tokens. These are then concatenated with the text
+ tokens, and send through the Transformer encoder. This means that the last hidden states of the model will have a
+ length of 512 + 49 = 561, if you pad the text tokens up to the max length. More generally, the last hidden states
+ will have a shape of `seq_length` + `image_feature_pool_shape[0]` *
+ `config.image_feature_pool_shape[1]`.
+- When calling [`~transformers.LayoutLMv2Model.from_pretrained`], a warning will be printed with a long list of
+ parameter names that are not initialized. This is not a problem, as these parameters are batch normalization
+ statistics, which are going to have values when fine-tuning on a custom dataset.
+- If you want to train the model in a distributed environment, make sure to call [`synchronize_batch_norm`] on the
+ model in order to properly synchronize the batch normalization layers of the visual backbone.
+
+In addition, there's LayoutXLM, which is a multilingual version of LayoutLMv2. More information can be found on
+[LayoutXLM's documentation page](layoutxlm).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LayoutLMv2. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- A notebook on how to [finetune LayoutLMv2 for text-classification on RVL-CDIP dataset](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/RVL-CDIP/Fine_tuning_LayoutLMv2ForSequenceClassification_on_RVL_CDIP.ipynb).
+- See also: [Text classification task guide](../tasks/sequence_classification)
+
+
+
+- A notebook on how to [finetune LayoutLMv2 for question-answering on DocVQA dataset](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/DocVQA/Fine_tuning_LayoutLMv2ForQuestionAnswering_on_DocVQA.ipynb).
+- See also: [Question answering task guide](../tasks/question_answering)
+- See also: [Document question answering task guide](../tasks/document_question_answering)
+
+
+
+
+- A notebook on how to [finetune LayoutLMv2 for token-classification on CORD dataset](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/CORD/Fine_tuning_LayoutLMv2ForTokenClassification_on_CORD.ipynb).
+- A notebook on how to [finetune LayoutLMv2 for token-classification on FUNSD dataset](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/FUNSD/Fine_tuning_LayoutLMv2ForTokenClassification_on_FUNSD_using_HuggingFace_Trainer.ipynb).
+- See also: [Token classification task guide](../tasks/token_classification)
+
+## Usage: LayoutLMv2Processor
+
+The easiest way to prepare data for the model is to use [`LayoutLMv2Processor`], which internally
+combines a image processor ([`LayoutLMv2ImageProcessor`]) and a tokenizer
+([`LayoutLMv2Tokenizer`] or [`LayoutLMv2TokenizerFast`]). The image processor
+handles the image modality, while the tokenizer handles the text modality. A processor combines both, which is ideal
+for a multi-modal model like LayoutLMv2. Note that you can still use both separately, if you only want to handle one
+modality.
+
+```python
+from transformers import LayoutLMv2ImageProcessor, LayoutLMv2TokenizerFast, LayoutLMv2Processor
+
+image_processor = LayoutLMv2ImageProcessor() # apply_ocr is set to True by default
+tokenizer = LayoutLMv2TokenizerFast.from_pretrained("microsoft/layoutlmv2-base-uncased")
+processor = LayoutLMv2Processor(image_processor, tokenizer)
+```
+
+In short, one can provide a document image (and possibly additional data) to [`LayoutLMv2Processor`],
+and it will create the inputs expected by the model. Internally, the processor first uses
+[`LayoutLMv2ImageProcessor`] to apply OCR on the image to get a list of words and normalized
+bounding boxes, as well to resize the image to a given size in order to get the `image` input. The words and
+normalized bounding boxes are then provided to [`LayoutLMv2Tokenizer`] or
+[`LayoutLMv2TokenizerFast`], which converts them to token-level `input_ids`,
+`attention_mask`, `token_type_ids`, `bbox`. Optionally, one can provide word labels to the processor,
+which are turned into token-level `labels`.
+
+[`LayoutLMv2Processor`] uses [PyTesseract](https://pypi.org/project/pytesseract/), a Python
+wrapper around Google's Tesseract OCR engine, under the hood. Note that you can still use your own OCR engine of
+choice, and provide the words and normalized boxes yourself. This requires initializing
+[`LayoutLMv2ImageProcessor`] with `apply_ocr` set to `False`.
+
+In total, there are 5 use cases that are supported by the processor. Below, we list them all. Note that each of these
+use cases work for both batched and non-batched inputs (we illustrate them for non-batched inputs).
+
+**Use case 1: document image classification (training, inference) + token classification (inference), apply_ocr =
+True**
+
+This is the simplest case, in which the processor (actually the image processor) will perform OCR on the image to get
+the words and normalized bounding boxes.
+
+```python
+from transformers import LayoutLMv2Processor
+from PIL import Image
+
+processor = LayoutLMv2Processor.from_pretrained("microsoft/layoutlmv2-base-uncased")
+
+image = Image.open(
+ "name_of_your_document - can be a png, jpg, etc. of your documents (PDFs must be converted to images)."
+).convert("RGB")
+encoding = processor(
+ image, return_tensors="pt"
+) # you can also add all tokenizer parameters here such as padding, truncation
+print(encoding.keys())
+# dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'bbox', 'image'])
+```
+
+**Use case 2: document image classification (training, inference) + token classification (inference), apply_ocr=False**
+
+In case one wants to do OCR themselves, one can initialize the image processor with `apply_ocr` set to
+`False`. In that case, one should provide the words and corresponding (normalized) bounding boxes themselves to
+the processor.
+
+```python
+from transformers import LayoutLMv2Processor
+from PIL import Image
+
+processor = LayoutLMv2Processor.from_pretrained("microsoft/layoutlmv2-base-uncased", revision="no_ocr")
+
+image = Image.open(
+ "name_of_your_document - can be a png, jpg, etc. of your documents (PDFs must be converted to images)."
+).convert("RGB")
+words = ["hello", "world"]
+boxes = [[1, 2, 3, 4], [5, 6, 7, 8]] # make sure to normalize your bounding boxes
+encoding = processor(image, words, boxes=boxes, return_tensors="pt")
+print(encoding.keys())
+# dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'bbox', 'image'])
+```
+
+**Use case 3: token classification (training), apply_ocr=False**
+
+For token classification tasks (such as FUNSD, CORD, SROIE, Kleister-NDA), one can also provide the corresponding word
+labels in order to train a model. The processor will then convert these into token-level `labels`. By default, it
+will only label the first wordpiece of a word, and label the remaining wordpieces with -100, which is the
+`ignore_index` of PyTorch's CrossEntropyLoss. In case you want all wordpieces of a word to be labeled, you can
+initialize the tokenizer with `only_label_first_subword` set to `False`.
+
+```python
+from transformers import LayoutLMv2Processor
+from PIL import Image
+
+processor = LayoutLMv2Processor.from_pretrained("microsoft/layoutlmv2-base-uncased", revision="no_ocr")
+
+image = Image.open(
+ "name_of_your_document - can be a png, jpg, etc. of your documents (PDFs must be converted to images)."
+).convert("RGB")
+words = ["hello", "world"]
+boxes = [[1, 2, 3, 4], [5, 6, 7, 8]] # make sure to normalize your bounding boxes
+word_labels = [1, 2]
+encoding = processor(image, words, boxes=boxes, word_labels=word_labels, return_tensors="pt")
+print(encoding.keys())
+# dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'bbox', 'labels', 'image'])
+```
+
+**Use case 4: visual question answering (inference), apply_ocr=True**
+
+For visual question answering tasks (such as DocVQA), you can provide a question to the processor. By default, the
+processor will apply OCR on the image, and create [CLS] question tokens [SEP] word tokens [SEP].
+
+```python
+from transformers import LayoutLMv2Processor
+from PIL import Image
+
+processor = LayoutLMv2Processor.from_pretrained("microsoft/layoutlmv2-base-uncased")
+
+image = Image.open(
+ "name_of_your_document - can be a png, jpg, etc. of your documents (PDFs must be converted to images)."
+).convert("RGB")
+question = "What's his name?"
+encoding = processor(image, question, return_tensors="pt")
+print(encoding.keys())
+# dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'bbox', 'image'])
+```
+
+**Use case 5: visual question answering (inference), apply_ocr=False**
+
+For visual question answering tasks (such as DocVQA), you can provide a question to the processor. If you want to
+perform OCR yourself, you can provide your own words and (normalized) bounding boxes to the processor.
+
+```python
+from transformers import LayoutLMv2Processor
+from PIL import Image
+
+processor = LayoutLMv2Processor.from_pretrained("microsoft/layoutlmv2-base-uncased", revision="no_ocr")
+
+image = Image.open(
+ "name_of_your_document - can be a png, jpg, etc. of your documents (PDFs must be converted to images)."
+).convert("RGB")
+question = "What's his name?"
+words = ["hello", "world"]
+boxes = [[1, 2, 3, 4], [5, 6, 7, 8]] # make sure to normalize your bounding boxes
+encoding = processor(image, question, words, boxes=boxes, return_tensors="pt")
+print(encoding.keys())
+# dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'bbox', 'image'])
+```
+
+## LayoutLMv2Config
+
+[[autodoc]] LayoutLMv2Config
+
+## LayoutLMv2FeatureExtractor
+
+[[autodoc]] LayoutLMv2FeatureExtractor
+ - __call__
+
+## LayoutLMv2ImageProcessor
+
+[[autodoc]] LayoutLMv2ImageProcessor
+ - preprocess
+
+## LayoutLMv2Tokenizer
+
+[[autodoc]] LayoutLMv2Tokenizer
+ - __call__
+ - save_vocabulary
+
+## LayoutLMv2TokenizerFast
+
+[[autodoc]] LayoutLMv2TokenizerFast
+ - __call__
+
+## LayoutLMv2Processor
+
+[[autodoc]] LayoutLMv2Processor
+ - __call__
+
+## LayoutLMv2Model
+
+[[autodoc]] LayoutLMv2Model
+ - forward
+
+## LayoutLMv2ForSequenceClassification
+
+[[autodoc]] LayoutLMv2ForSequenceClassification
+
+## LayoutLMv2ForTokenClassification
+
+[[autodoc]] LayoutLMv2ForTokenClassification
+
+## LayoutLMv2ForQuestionAnswering
+
+[[autodoc]] LayoutLMv2ForQuestionAnswering
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/layoutlmv3.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/layoutlmv3.md
new file mode 100644
index 0000000000000000000000000000000000000000..87ff32f3835690bbe15214ae0dd4aa56c638b5b0
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/layoutlmv3.md
@@ -0,0 +1,154 @@
+
+
+# LayoutLMv3
+
+## Overview
+
+The LayoutLMv3 model was proposed in [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://arxiv.org/abs/2204.08387) by Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei.
+LayoutLMv3 simplifies [LayoutLMv2](layoutlmv2) by using patch embeddings (as in [ViT](vit)) instead of leveraging a CNN backbone, and pre-trains the model on 3 objectives: masked language modeling (MLM), masked image modeling (MIM)
+and word-patch alignment (WPA).
+
+The abstract from the paper is the following:
+
+*Self-supervised pre-training techniques have achieved remarkable progress in Document AI. Most multimodal pre-trained models use a masked language modeling objective to learn bidirectional representations on the text modality, but they differ in pre-training objectives for the image modality. This discrepancy adds difficulty to multimodal representation learning. In this paper, we propose LayoutLMv3 to pre-train multimodal Transformers for Document AI with unified text and image masking. Additionally, LayoutLMv3 is pre-trained with a word-patch alignment objective to learn cross-modal alignment by predicting whether the corresponding image patch of a text word is masked. The simple unified architecture and training objectives make LayoutLMv3 a general-purpose pre-trained model for both text-centric and image-centric Document AI tasks. Experimental results show that LayoutLMv3 achieves state-of-the-art performance not only in text-centric tasks, including form understanding, receipt understanding, and document visual question answering, but also in image-centric tasks such as document image classification and document layout analysis.*
+
+
+
+ LayoutLMv3 architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The TensorFlow version of this model was added by [chriskoo](https://huggingface.co/chriskoo), [tokec](https://huggingface.co/tokec), and [lre](https://huggingface.co/lre). The original code can be found [here](https://github.com/microsoft/unilm/tree/master/layoutlmv3).
+
+## Usage tips
+
+- In terms of data processing, LayoutLMv3 is identical to its predecessor [LayoutLMv2](layoutlmv2), except that:
+ - images need to be resized and normalized with channels in regular RGB format. LayoutLMv2 on the other hand normalizes the images internally and expects the channels in BGR format.
+ - text is tokenized using byte-pair encoding (BPE), as opposed to WordPiece.
+ Due to these differences in data preprocessing, one can use [`LayoutLMv3Processor`] which internally combines a [`LayoutLMv3ImageProcessor`] (for the image modality) and a [`LayoutLMv3Tokenizer`]/[`LayoutLMv3TokenizerFast`] (for the text modality) to prepare all data for the model.
+- Regarding usage of [`LayoutLMv3Processor`], we refer to the [usage guide](layoutlmv2#usage-layoutlmv2processor) of its predecessor.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LayoutLMv3. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+LayoutLMv3 is nearly identical to LayoutLMv2, so we've also included LayoutLMv2 resources you can adapt for LayoutLMv3 tasks. For these notebooks, take care to use [`LayoutLMv2Processor`] instead when preparing data for the model!
+
+
+
+- Demo notebooks for LayoutLMv3 can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/LayoutLMv3).
+- Demo scripts can be found [here](https://github.com/huggingface/transformers/tree/main/examples/research_projects/layoutlmv3).
+
+
+
+- [`LayoutLMv2ForSequenceClassification`] is supported by this [notebook](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/RVL-CDIP/Fine_tuning_LayoutLMv2ForSequenceClassification_on_RVL_CDIP.ipynb).
+- [Text classification task guide](../tasks/sequence_classification)
+
+
+
+- [`LayoutLMv3ForTokenClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/research_projects/layoutlmv3) and [notebook](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv3/Fine_tune_LayoutLMv3_on_FUNSD_(HuggingFace_Trainer).ipynb).
+- A [notebook](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/FUNSD/Inference_with_LayoutLMv2ForTokenClassification.ipynb) for how to perform inference with [`LayoutLMv2ForTokenClassification`] and a [notebook](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/FUNSD/True_inference_with_LayoutLMv2ForTokenClassification_%2B_Gradio_demo.ipynb) for how to perform inference when no labels are available with [`LayoutLMv2ForTokenClassification`].
+- A [notebook](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/FUNSD/Fine_tuning_LayoutLMv2ForTokenClassification_on_FUNSD_using_HuggingFace_Trainer.ipynb) for how to finetune [`LayoutLMv2ForTokenClassification`] with the 🤗 Trainer.
+- [Token classification task guide](../tasks/token_classification)
+
+
+
+- [`LayoutLMv2ForQuestionAnswering`] is supported by this [notebook](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/DocVQA/Fine_tuning_LayoutLMv2ForQuestionAnswering_on_DocVQA.ipynb).
+- [Question answering task guide](../tasks/question_answering)
+
+**Document question answering**
+- [Document question answering task guide](../tasks/document_question_answering)
+
+## LayoutLMv3Config
+
+[[autodoc]] LayoutLMv3Config
+
+## LayoutLMv3FeatureExtractor
+
+[[autodoc]] LayoutLMv3FeatureExtractor
+ - __call__
+
+## LayoutLMv3ImageProcessor
+
+[[autodoc]] LayoutLMv3ImageProcessor
+ - preprocess
+
+## LayoutLMv3Tokenizer
+
+[[autodoc]] LayoutLMv3Tokenizer
+ - __call__
+ - save_vocabulary
+
+## LayoutLMv3TokenizerFast
+
+[[autodoc]] LayoutLMv3TokenizerFast
+ - __call__
+
+## LayoutLMv3Processor
+
+[[autodoc]] LayoutLMv3Processor
+ - __call__
+
+
+
+
+## LayoutLMv3Model
+
+[[autodoc]] LayoutLMv3Model
+ - forward
+
+## LayoutLMv3ForSequenceClassification
+
+[[autodoc]] LayoutLMv3ForSequenceClassification
+ - forward
+
+## LayoutLMv3ForTokenClassification
+
+[[autodoc]] LayoutLMv3ForTokenClassification
+ - forward
+
+## LayoutLMv3ForQuestionAnswering
+
+[[autodoc]] LayoutLMv3ForQuestionAnswering
+ - forward
+
+
+
+
+## TFLayoutLMv3Model
+
+[[autodoc]] TFLayoutLMv3Model
+ - call
+
+## TFLayoutLMv3ForSequenceClassification
+
+[[autodoc]] TFLayoutLMv3ForSequenceClassification
+ - call
+
+## TFLayoutLMv3ForTokenClassification
+
+[[autodoc]] TFLayoutLMv3ForTokenClassification
+ - call
+
+## TFLayoutLMv3ForQuestionAnswering
+
+[[autodoc]] TFLayoutLMv3ForQuestionAnswering
+ - call
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/layoutxlm.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/layoutxlm.md
new file mode 100644
index 0000000000000000000000000000000000000000..f6b2cbef9d6fd111efeb8a9169d820272bc66d0b
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/layoutxlm.md
@@ -0,0 +1,85 @@
+
+
+# LayoutXLM
+
+## Overview
+
+LayoutXLM was proposed in [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://arxiv.org/abs/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha
+Zhang, Furu Wei. It's a multilingual extension of the [LayoutLMv2 model](https://arxiv.org/abs/2012.14740) trained
+on 53 languages.
+
+The abstract from the paper is the following:
+
+*Multimodal pre-training with text, layout, and image has achieved SOTA performance for visually-rich document
+understanding tasks recently, which demonstrates the great potential for joint learning across different modalities. In
+this paper, we present LayoutXLM, a multimodal pre-trained model for multilingual document understanding, which aims to
+bridge the language barriers for visually-rich document understanding. To accurately evaluate LayoutXLM, we also
+introduce a multilingual form understanding benchmark dataset named XFUN, which includes form understanding samples in
+7 languages (Chinese, Japanese, Spanish, French, Italian, German, Portuguese), and key-value pairs are manually labeled
+for each language. Experiment results show that the LayoutXLM model has significantly outperformed the existing SOTA
+cross-lingual pre-trained models on the XFUN dataset.*
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found [here](https://github.com/microsoft/unilm).
+
+## Usage tips and examples
+
+One can directly plug in the weights of LayoutXLM into a LayoutLMv2 model, like so:
+
+```python
+from transformers import LayoutLMv2Model
+
+model = LayoutLMv2Model.from_pretrained("microsoft/layoutxlm-base")
+```
+
+Note that LayoutXLM has its own tokenizer, based on
+[`LayoutXLMTokenizer`]/[`LayoutXLMTokenizerFast`]. You can initialize it as
+follows:
+
+```python
+from transformers import LayoutXLMTokenizer
+
+tokenizer = LayoutXLMTokenizer.from_pretrained("microsoft/layoutxlm-base")
+```
+
+Similar to LayoutLMv2, you can use [`LayoutXLMProcessor`] (which internally applies
+[`LayoutLMv2ImageProcessor`] and
+[`LayoutXLMTokenizer`]/[`LayoutXLMTokenizerFast`] in sequence) to prepare all
+data for the model.
+
+
+
+As LayoutXLM's architecture is equivalent to that of LayoutLMv2, one can refer to [LayoutLMv2's documentation page](layoutlmv2) for all tips, code examples and notebooks.
+
+
+## LayoutXLMTokenizer
+
+[[autodoc]] LayoutXLMTokenizer
+ - __call__
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## LayoutXLMTokenizerFast
+
+[[autodoc]] LayoutXLMTokenizerFast
+ - __call__
+
+## LayoutXLMProcessor
+
+[[autodoc]] LayoutXLMProcessor
+ - __call__
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/led.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/led.md
new file mode 100644
index 0000000000000000000000000000000000000000..9a39b0b28eded21a6c138d3d2589b097f90969c2
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/led.md
@@ -0,0 +1,143 @@
+
+
+# LED
+
+## Overview
+
+The LED model was proposed in [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz
+Beltagy, Matthew E. Peters, Arman Cohan.
+
+The abstract from the paper is the following:
+
+*Transformer-based models are unable to process long sequences due to their self-attention operation, which scales
+quadratically with the sequence length. To address this limitation, we introduce the Longformer with an attention
+mechanism that scales linearly with sequence length, making it easy to process documents of thousands of tokens or
+longer. Longformer's attention mechanism is a drop-in replacement for the standard self-attention and combines a local
+windowed attention with a task motivated global attention. Following prior work on long-sequence transformers, we
+evaluate Longformer on character-level language modeling and achieve state-of-the-art results on text8 and enwik8. In
+contrast to most prior work, we also pretrain Longformer and finetune it on a variety of downstream tasks. Our
+pretrained Longformer consistently outperforms RoBERTa on long document tasks and sets new state-of-the-art results on
+WikiHop and TriviaQA. We finally introduce the Longformer-Encoder-Decoder (LED), a Longformer variant for supporting
+long document generative sequence-to-sequence tasks, and demonstrate its effectiveness on the arXiv summarization
+dataset.*
+
+## Usage tips
+
+- [`LEDForConditionalGeneration`] is an extension of
+ [`BartForConditionalGeneration`] exchanging the traditional *self-attention* layer with
+ *Longformer*'s *chunked self-attention* layer. [`LEDTokenizer`] is an alias of
+ [`BartTokenizer`].
+- LED works very well on long-range *sequence-to-sequence* tasks where the `input_ids` largely exceed a length of
+ 1024 tokens.
+- LED pads the `input_ids` to be a multiple of `config.attention_window` if required. Therefore a small speed-up is
+ gained, when [`LEDTokenizer`] is used with the `pad_to_multiple_of` argument.
+- LED makes use of *global attention* by means of the `global_attention_mask` (see
+ [`LongformerModel`]). For summarization, it is advised to put *global attention* only on the first
+ `` token. For question answering, it is advised to put *global attention* on all tokens of the question.
+- To fine-tune LED on all 16384, *gradient checkpointing* can be enabled in case training leads to out-of-memory (OOM)
+ errors. This can be done by executing `model.gradient_checkpointing_enable()`.
+ Moreover, the `use_cache=False`
+ flag can be used to disable the caching mechanism to save memory.
+- LED is a model with absolute position embeddings so it's usually advised to pad the inputs on the right rather than
+ the left.
+
+This model was contributed by [patrickvonplaten](https://huggingface.co/patrickvonplaten).
+
+## Resources
+
+- [A notebook showing how to evaluate LED](https://colab.research.google.com/drive/12INTTR6n64TzS4RrXZxMSXfrOd9Xzamo?usp=sharing).
+- [A notebook showing how to fine-tune LED](https://colab.research.google.com/drive/12LjJazBl7Gam0XBPy_y0CTOJZeZ34c2v?usp=sharing).
+- [Text classification task guide](../tasks/sequence_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## LEDConfig
+
+[[autodoc]] LEDConfig
+
+## LEDTokenizer
+
+[[autodoc]] LEDTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## LEDTokenizerFast
+
+[[autodoc]] LEDTokenizerFast
+
+## LED specific outputs
+
+[[autodoc]] models.led.modeling_led.LEDEncoderBaseModelOutput
+
+[[autodoc]] models.led.modeling_led.LEDSeq2SeqModelOutput
+
+[[autodoc]] models.led.modeling_led.LEDSeq2SeqLMOutput
+
+[[autodoc]] models.led.modeling_led.LEDSeq2SeqSequenceClassifierOutput
+
+[[autodoc]] models.led.modeling_led.LEDSeq2SeqQuestionAnsweringModelOutput
+
+[[autodoc]] models.led.modeling_tf_led.TFLEDEncoderBaseModelOutput
+
+[[autodoc]] models.led.modeling_tf_led.TFLEDSeq2SeqModelOutput
+
+[[autodoc]] models.led.modeling_tf_led.TFLEDSeq2SeqLMOutput
+
+
+
+
+## LEDModel
+
+[[autodoc]] LEDModel
+ - forward
+
+## LEDForConditionalGeneration
+
+[[autodoc]] LEDForConditionalGeneration
+ - forward
+
+## LEDForSequenceClassification
+
+[[autodoc]] LEDForSequenceClassification
+ - forward
+
+## LEDForQuestionAnswering
+
+[[autodoc]] LEDForQuestionAnswering
+ - forward
+
+
+
+
+## TFLEDModel
+
+[[autodoc]] TFLEDModel
+ - call
+
+## TFLEDForConditionalGeneration
+
+[[autodoc]] TFLEDForConditionalGeneration
+ - call
+
+
+
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/levit.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/levit.md
new file mode 100644
index 0000000000000000000000000000000000000000..15dc2f4e137357f02c12820a37efb08a18de9981
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/levit.md
@@ -0,0 +1,106 @@
+
+
+# LeViT
+
+## Overview
+
+The LeViT model was proposed in [LeViT: Introducing Convolutions to Vision Transformers](https://arxiv.org/abs/2104.01136) by Ben Graham, Alaaeldin El-Nouby, Hugo Touvron, Pierre Stock, Armand Joulin, Hervé Jégou, Matthijs Douze. LeViT improves the [Vision Transformer (ViT)](vit) in performance and efficiency by a few architectural differences such as activation maps with decreasing resolutions in Transformers and the introduction of an attention bias to integrate positional information.
+
+The abstract from the paper is the following:
+
+*We design a family of image classification architectures that optimize the trade-off between accuracy
+and efficiency in a high-speed regime. Our work exploits recent findings in attention-based architectures,
+which are competitive on highly parallel processing hardware. We revisit principles from the extensive
+literature on convolutional neural networks to apply them to transformers, in particular activation maps
+with decreasing resolutions. We also introduce the attention bias, a new way to integrate positional information
+in vision transformers. As a result, we propose LeVIT: a hybrid neural network for fast inference image classification.
+We consider different measures of efficiency on different hardware platforms, so as to best reflect a wide range of
+application scenarios. Our extensive experiments empirically validate our technical choices and show they are suitable
+to most architectures. Overall, LeViT significantly outperforms existing convnets and vision transformers with respect
+to the speed/accuracy tradeoff. For example, at 80% ImageNet top-1 accuracy, LeViT is 5 times faster than EfficientNet on CPU. *
+
+
+
+ LeViT Architecture. Taken from the original paper.
+
+This model was contributed by [anugunj](https://huggingface.co/anugunj). The original code can be found [here](https://github.com/facebookresearch/LeViT).
+
+## Usage tips
+
+- Compared to ViT, LeViT models use an additional distillation head to effectively learn from a teacher (which, in the LeViT paper, is a ResNet like-model). The distillation head is learned through backpropagation under supervision of a ResNet like-model. They also draw inspiration from convolution neural networks to use activation maps with decreasing resolutions to increase the efficiency.
+- There are 2 ways to fine-tune distilled models, either (1) in a classic way, by only placing a prediction head on top
+ of the final hidden state and not using the distillation head, or (2) by placing both a prediction head and distillation
+ head on top of the final hidden state. In that case, the prediction head is trained using regular cross-entropy between
+ the prediction of the head and the ground-truth label, while the distillation prediction head is trained using hard distillation
+ (cross-entropy between the prediction of the distillation head and the label predicted by the teacher). At inference time,
+ one takes the average prediction between both heads as final prediction. (2) is also called "fine-tuning with distillation",
+ because one relies on a teacher that has already been fine-tuned on the downstream dataset. In terms of models, (1) corresponds
+ to [`LevitForImageClassification`] and (2) corresponds to [`LevitForImageClassificationWithTeacher`].
+- All released checkpoints were pre-trained and fine-tuned on [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k)
+ (also referred to as ILSVRC 2012, a collection of 1.3 million images and 1,000 classes). only. No external data was used. This is in
+ contrast with the original ViT model, which used external data like the JFT-300M dataset/Imagenet-21k for
+ pre-training.
+- The authors of LeViT released 5 trained LeViT models, which you can directly plug into [`LevitModel`] or [`LevitForImageClassification`].
+ Techniques like data augmentation, optimization, and regularization were used in order to simulate training on a much larger dataset
+ (while only using ImageNet-1k for pre-training). The 5 variants available are (all trained on images of size 224x224):
+ *facebook/levit-128S*, *facebook/levit-128*, *facebook/levit-192*, *facebook/levit-256* and
+ *facebook/levit-384*. Note that one should use [`LevitImageProcessor`] in order to
+ prepare images for the model.
+- [`LevitForImageClassificationWithTeacher`] currently supports only inference and not training or fine-tuning.
+- You can check out demo notebooks regarding inference as well as fine-tuning on custom data [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/VisionTransformer)
+ (you can just replace [`ViTFeatureExtractor`] by [`LevitImageProcessor`] and [`ViTForImageClassification`] by [`LevitForImageClassification`] or [`LevitForImageClassificationWithTeacher`]).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LeViT.
+
+
+
+- [`LevitForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## LevitConfig
+
+[[autodoc]] LevitConfig
+
+## LevitFeatureExtractor
+
+[[autodoc]] LevitFeatureExtractor
+ - __call__
+
+## LevitImageProcessor
+
+ [[autodoc]] LevitImageProcessor
+ - preprocess
+
+## LevitModel
+
+[[autodoc]] LevitModel
+ - forward
+
+## LevitForImageClassification
+
+[[autodoc]] LevitForImageClassification
+ - forward
+
+## LevitForImageClassificationWithTeacher
+
+[[autodoc]] LevitForImageClassificationWithTeacher
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/lilt.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/lilt.md
new file mode 100644
index 0000000000000000000000000000000000000000..2514a6ebd85263ebb5782cb4d892edd8a2ba1dbc
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/lilt.md
@@ -0,0 +1,88 @@
+
+
+# LiLT
+
+## Overview
+
+The LiLT model was proposed in [LiLT: A Simple yet Effective Language-Independent Layout Transformer for Structured Document Understanding](https://arxiv.org/abs/2202.13669) by Jiapeng Wang, Lianwen Jin, Kai Ding.
+LiLT allows to combine any pre-trained RoBERTa text encoder with a lightweight Layout Transformer, to enable [LayoutLM](layoutlm)-like document understanding for many
+languages.
+
+The abstract from the paper is the following:
+
+*Structured document understanding has attracted considerable attention and made significant progress recently, owing to its crucial role in intelligent document processing. However, most existing related models can only deal with the document data of specific language(s) (typically English) included in the pre-training collection, which is extremely limited. To address this issue, we propose a simple yet effective Language-independent Layout Transformer (LiLT) for structured document understanding. LiLT can be pre-trained on the structured documents of a single language and then directly fine-tuned on other languages with the corresponding off-the-shelf monolingual/multilingual pre-trained textual models. Experimental results on eight languages have shown that LiLT can achieve competitive or even superior performance on diverse widely-used downstream benchmarks, which enables language-independent benefit from the pre-training of document layout structure.*
+
+
+
+ LiLT architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/jpwang/lilt).
+
+## Usage tips
+
+- To combine the Language-Independent Layout Transformer with a new RoBERTa checkpoint from the [hub](https://huggingface.co/models?search=roberta), refer to [this guide](https://github.com/jpWang/LiLT#or-generate-your-own-checkpoint-optional).
+The script will result in `config.json` and `pytorch_model.bin` files being stored locally. After doing this, one can do the following (assuming you're logged in with your HuggingFace account):
+
+```python
+from transformers import LiltModel
+
+model = LiltModel.from_pretrained("path_to_your_files")
+model.push_to_hub("name_of_repo_on_the_hub")
+```
+
+- When preparing data for the model, make sure to use the token vocabulary that corresponds to the RoBERTa checkpoint you combined with the Layout Transformer.
+- As [lilt-roberta-en-base](https://huggingface.co/SCUT-DLVCLab/lilt-roberta-en-base) uses the same vocabulary as [LayoutLMv3](layoutlmv3), one can use [`LayoutLMv3TokenizerFast`] to prepare data for the model.
+The same is true for [lilt-roberta-en-base](https://huggingface.co/SCUT-DLVCLab/lilt-infoxlm-base): one can use [`LayoutXLMTokenizerFast`] for that model.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LiLT.
+
+- Demo notebooks for LiLT can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/LiLT).
+
+**Documentation resources**
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## LiltConfig
+
+[[autodoc]] LiltConfig
+
+## LiltModel
+
+[[autodoc]] LiltModel
+ - forward
+
+## LiltForSequenceClassification
+
+[[autodoc]] LiltForSequenceClassification
+ - forward
+
+## LiltForTokenClassification
+
+[[autodoc]] LiltForTokenClassification
+ - forward
+
+## LiltForQuestionAnswering
+
+[[autodoc]] LiltForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llama.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llama.md
new file mode 100644
index 0000000000000000000000000000000000000000..2f0eb63da00a84278d4da782e09a84620d58c963
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llama.md
@@ -0,0 +1,137 @@
+
+
+# LLaMA
+
+## Overview
+
+The LLaMA model was proposed in [LLaMA: Open and Efficient Foundation Language Models](https://arxiv.org/abs/2302.13971) by Hugo Touvron, Thibaut Lavril, Gautier Izacard, Xavier Martinet, Marie-Anne Lachaux, Timothée Lacroix, Baptiste Rozière, Naman Goyal, Eric Hambro, Faisal Azhar, Aurelien Rodriguez, Armand Joulin, Edouard Grave, Guillaume Lample. It is a collection of foundation language models ranging from 7B to 65B parameters.
+
+The abstract from the paper is the following:
+
+*We introduce LLaMA, a collection of foundation language models ranging from 7B to 65B parameters. We train our models on trillions of tokens, and show that it is possible to train state-of-the-art models using publicly available datasets exclusively, without resorting to proprietary and inaccessible datasets. In particular, LLaMA-13B outperforms GPT-3 (175B) on most benchmarks, and LLaMA-65B is competitive with the best models, Chinchilla-70B and PaLM-540B. We release all our models to the research community. *
+
+This model was contributed by [zphang](https://huggingface.co/zphang) with contributions from [BlackSamorez](https://huggingface.co/BlackSamorez). The code of the implementation in Hugging Face is based on GPT-NeoX [here](https://github.com/EleutherAI/gpt-neox). The original code of the authors can be found [here](https://github.com/facebookresearch/llama).
+
+## Usage tips
+
+- Weights for the LLaMA models can be obtained from by filling out [this form](https://docs.google.com/forms/d/e/1FAIpQLSfqNECQnMkycAp2jP4Z9TFX0cGR4uf7b_fBxjY_OjhJILlKGA/viewform?usp=send_form)
+- After downloading the weights, they will need to be converted to the Hugging Face Transformers format using the [conversion script](https://github.com/huggingface/transformers/blob/main/src/transformers/models/llama/convert_llama_weights_to_hf.py). The script can be called with the following (example) command:
+
+```bash
+python src/transformers/models/llama/convert_llama_weights_to_hf.py \
+ --input_dir /path/to/downloaded/llama/weights --model_size 7B --output_dir /output/path
+```
+
+- After conversion, the model and tokenizer can be loaded via:
+
+```python
+from transformers import LlamaForCausalLM, LlamaTokenizer
+
+tokenizer = LlamaTokenizer.from_pretrained("/output/path")
+model = LlamaForCausalLM.from_pretrained("/output/path")
+```
+
+Note that executing the script requires enough CPU RAM to host the whole model in float16 precision (even if the biggest versions
+come in several checkpoints they each contain a part of each weight of the model, so we need to load them all in RAM). For the 65B model, it's thus 130GB of RAM needed.
+
+- The LLaMA tokenizer is a BPE model based on [sentencepiece](https://github.com/google/sentencepiece). One quirk of sentencepiece is that when decoding a sequence, if the first token is the start of the word (e.g. "Banana"), the tokenizer does not prepend the prefix space to the string.
+
+This model was contributed by [zphang](https://huggingface.co/zphang) with contributions from [BlackSamorez](https://huggingface.co/BlackSamorez). The code of the implementation in Hugging Face is based on GPT-NeoX [here](https://github.com/EleutherAI/gpt-neox). The original code of the authors can be found [here](https://github.com/facebookresearch/llama). The Flax version of the implementation was contributed by [afmck](https://huggingface.co/afmck) with the code in the implementation based on Hugging Face's Flax GPT-Neo.
+
+
+Based on the original LLaMA model, Meta AI has released some follow-up works:
+
+- **Llama2**: Llama2 is an improved version of Llama with some architectural tweaks (Grouped Query Attention), and is pre-trained on 2Trillion tokens. Refer to the documentation of Llama2 which can be found [here](llama2).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LLaMA. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- A [notebook](https://colab.research.google.com/github/bigscience-workshop/petals/blob/main/examples/prompt-tuning-sst2.ipynb#scrollTo=f04ba4d2) on how to use prompt tuning to adapt the LLaMA model for text classification task. 🌎
+
+
+
+- [StackLLaMA: A hands-on guide to train LLaMA with RLHF](https://huggingface.co/blog/stackllama#stackllama-a-hands-on-guide-to-train-llama-with-rlhf), a blog post about how to train LLaMA to answer questions on [Stack Exchange](https://stackexchange.com/) with RLHF.
+
+⚗️ Optimization
+- A [notebook](https://colab.research.google.com/drive/1SQUXq1AMZPSLD4mk3A3swUIc6Y2dclme?usp=sharing) on how to fine-tune LLaMA model using xturing library on GPU which has limited memory. 🌎
+
+⚡️ Inference
+- A [notebook](https://colab.research.google.com/github/DominguesM/alpaca-lora-ptbr-7b/blob/main/notebooks/02%20-%20Evaluate.ipynb) on how to run the LLaMA Model using PeftModel from the 🤗 PEFT library. 🌎
+- A [notebook](https://colab.research.google.com/drive/1l2GiSSPbajVyp2Nk3CFT4t3uH6-5TiBe?usp=sharing) on how to load a PEFT adapter LLaMA model with LangChain. 🌎
+
+🚀 Deploy
+- A [notebook](https://colab.research.google.com/github/lxe/simple-llama-finetuner/blob/master/Simple_LLaMA_FineTuner.ipynb#scrollTo=3PM_DilAZD8T) on how to fine-tune LLaMA model using LoRA method via the 🤗 PEFT library with intuitive UI. 🌎
+- A [notebook](https://github.com/aws/amazon-sagemaker-examples/blob/main/introduction_to_amazon_algorithms/jumpstart-foundation-models/text-generation-open-llama.ipynb) on how to deploy Open-LLaMA model for text generation on Amazon SageMaker. 🌎
+
+## LlamaConfig
+
+[[autodoc]] LlamaConfig
+
+## LlamaTokenizer
+
+[[autodoc]] LlamaTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## LlamaTokenizerFast
+
+[[autodoc]] LlamaTokenizerFast
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - update_post_processor
+ - save_vocabulary
+
+## LlamaModel
+
+[[autodoc]] LlamaModel
+ - forward
+
+## LlamaForCausalLM
+
+[[autodoc]] LlamaForCausalLM
+ - forward
+
+## LlamaForSequenceClassification
+
+[[autodoc]] LlamaForSequenceClassification
+ - forward
+
+## LlamaForQuestionAnswering
+
+[[autodoc]] LlamaForQuestionAnswering
+ - forward
+
+## LlamaForTokenClassification
+
+[[autodoc]] LlamaForTokenClassification
+ - forward
+
+## FlaxLlamaModel
+
+[[autodoc]] FlaxLlamaModel
+ - __call__
+
+## FlaxLlamaForCausalLM
+
+[[autodoc]] FlaxLlamaForCausalLM
+ - __call__
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llama2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llama2.md
new file mode 100644
index 0000000000000000000000000000000000000000..b4cd6b9ca110d145c687ce2acc092c32fe14e5b5
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llama2.md
@@ -0,0 +1,140 @@
+
+
+# Llama2
+
+## Overview
+
+The Llama2 model was proposed in [LLaMA: Open Foundation and Fine-Tuned Chat Models](https://ai.meta.com/research/publications/llama-2-open-foundation-and-fine-tuned-chat-models/) by Hugo Touvron, Louis Martin, Kevin Stone, Peter Albert, Amjad Almahairi, Yasmine Babaei, Nikolay Bashlykov, Soumya Batra, Prajjwal Bhargava, Shruti Bhosale, Dan Bikel, Lukas Blecher, Cristian Canton Ferrer, Moya Chen, Guillem Cucurull, David Esiobu, Jude Fernandes, Jeremy Fu, Wenyin Fu, Brian Fuller, Cynthia Gao, Vedanuj Goswami, Naman Goyal, Anthony Hartshorn, Saghar Hosseini, Rui Hou, Hakan Inan, Marcin Kardas, Viktor Kerkez Madian Khabsa, Isabel Kloumann, Artem Korenev, Punit Singh Koura, Marie-Anne Lachaux, Thibaut Lavril, Jenya Lee, Diana Liskovich, Yinghai Lu, Yuning Mao, Xavier Martinet, Todor Mihaylov, Pushka rMishra, Igor Molybog, Yixin Nie, Andrew Poulton, Jeremy Reizenstein, Rashi Rungta, Kalyan Saladi, Alan Schelten, Ruan Silva, Eric Michael Smith, Ranjan Subramanian, Xiaoqing EllenTan, Binh Tang, Ross Taylor, Adina Williams, Jian Xiang Kuan, Puxin Xu, Zheng Yan, Iliyan Zarov, Yuchen Zhang, Angela Fan, Melanie Kambadur, Sharan Narang, Aurelien Rodriguez, Robert Stojnic, Sergey Edunov, Thomas Scialom. It is a collection of foundation language models ranging from 7B to 70B parameters, with checkpoints finetuned for chat application!
+
+The abstract from the paper is the following:
+
+*In this work, we develop and release Llama 2, a collection of pretrained and fine-tuned large language models (LLMs) ranging in scale from 7 billion to 70 billion parameters. Our fine-tuned LLMs, called Llama 2-Chat, are optimized for dialogue use cases. Our models outperform open-source chat models on most benchmarks we tested, and based on our human evaluations for helpfulness and safety, may be a suitable substitute for closed-source models. We provide a detailed description of our approach to fine-tuning and safety improvements of Llama 2-Chat in order to enable the community to build on our work and contribute to the responsible development of LLMs.*
+
+Checkout all Llama2 model checkpoints [here](https://huggingface.co/models?search=llama2).
+This model was contributed by [Arthur Zucker](https://huggingface.co/ArthurZ) with contributions from [Lysandre Debut](https://huggingface.co/lysandre). The code of the implementation in Hugging Face is based on GPT-NeoX [here](https://github.com/EleutherAI/gpt-neox). The original code of the authors can be found [here](https://github.com/facebookresearch/llama).
+
+## Usage tips
+
+
+
+The `Llama2` models were trained using `bfloat16`, but the original inference uses `float16`. The checkpoints uploaded on the Hub use `torch_dtype = 'float16'`, which will be
+used by the `AutoModel` API to cast the checkpoints from `torch.float32` to `torch.float16`.
+
+The `dtype` of the online weights is mostly irrelevant unless you are using `torch_dtype="auto"` when initializing a model using `model = AutoModelForCausalLM.from_pretrained("path", torch_dtype = "auto")`. The reason is that the model will first be downloaded ( using the `dtype` of the checkpoints online), then it will be casted to the default `dtype` of `torch` (becomes `torch.float32`), and finally, if there is a `torch_dtype` provided in the config, it will be used.
+
+Training the model in `float16` is not recommended and is known to produce `nan`; as such, the model should be trained in `bfloat16`.
+
+
+
+Tips:
+
+- Weights for the Llama2 models can be obtained by filling out [this form](https://ai.meta.com/resources/models-and-libraries/llama-downloads/)
+- The architecture is very similar to the first Llama, with the addition of Grouped Query Attention (GQA) following this [paper](https://arxiv.org/pdf/2305.13245.pdf)
+- Setting `config.pretraining_tp` to a value different than 1 will activate the more accurate but slower computation of the linear layers, which should better match the original logits.
+- The original model uses `pad_id = -1` which means that there is no padding token. We can't have the same logic, make sure to add a padding token using `tokenizer.add_special_tokens({"pad_token":""})` and resize the token embedding accordingly. You should also set the `model.config.pad_token_id`. The `embed_tokens` layer of the model is initialized with `self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.config.padding_idx)`, which makes sure that encoding the padding token will output zeros, so passing it when initializing is recommended.
+- After filling out the form and gaining access to the model checkpoints, you should be able to use the already converted checkpoints. Otherwise, if you are converting your own model, feel free to use the [conversion script](https://github.com/huggingface/transformers/blob/main/src/transformers/models/llama/convert_llama_weights_to_hf.py). The script can be called with the following (example) command:
+
+```bash
+python src/transformers/models/llama/convert_llama_weights_to_hf.py \
+ --input_dir /path/to/downloaded/llama/weights --model_size 7B --output_dir /output/path
+```
+
+- After conversion, the model and tokenizer can be loaded via:
+
+```python
+from transformers import LlamaForCausalLM, LlamaTokenizer
+
+tokenizer = LlamaTokenizer.from_pretrained("/output/path")
+model = LlamaForCausalLM.from_pretrained("/output/path")
+```
+
+Note that executing the script requires enough CPU RAM to host the whole model in float16 precision (even if the biggest versions
+come in several checkpoints they each contain a part of each weight of the model, so we need to load them all in RAM). For the 75B model, it's thus 145GB of RAM needed.
+
+- The LLaMA tokenizer is a BPE model based on [sentencepiece](https://github.com/google/sentencepiece). One quirk of sentencepiece is that when decoding a sequence, if the first token is the start of the word (e.g. "Banana"), the tokenizer does not prepend the prefix space to the string.
+
+- When using Flash Attention 2 via `attn_implementation="flash_attention_2"`, don't pass `torch_dtype` to the `from_pretrained` class method and use Automatic Mixed-Precision training. When using `Trainer`, it is simply specifying either `fp16` or `bf16` to `True`. Otherwise, make sure you are using `torch.autocast`. This is required because the Flash Attention only support `fp16` and `bf16` data type.
+
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LLaMA2. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- [Llama 2 is here - get it on Hugging Face](https://huggingface.co/blog/llama2), a blog post about Llama 2 and how to use it with 🤗 Transformers and 🤗 PEFT.
+- [LLaMA 2 - Every Resource you need](https://www.philschmid.de/llama-2), a compilation of relevant resources to learn about LLaMA 2 and how to get started quickly.
+
+
+
+- A [notebook](https://colab.research.google.com/drive/1PEQyJO1-f6j0S_XJ8DV50NkpzasXkrzd?usp=sharing) on how to fine-tune Llama 2 in Google Colab using QLoRA and 4-bit precision. 🌎
+- A [notebook](https://colab.research.google.com/drive/134o_cXcMe_lsvl15ZE_4Y75Kstepsntu?usp=sharing) on how to fine-tune the "Llama-v2-7b-guanaco" model with 4-bit QLoRA and generate Q&A datasets from PDFs. 🌎
+
+
+
+- A [notebook](https://colab.research.google.com/drive/1ggaa2oRFphdBmqIjSEbnb_HGkcIRC2ZB?usp=sharing) on how to fine-tune the Llama 2 model with QLoRa, TRL, and Korean text classification dataset. 🌎🇰🇷
+
+⚗️ Optimization
+- [Fine-tune Llama 2 with DPO](https://huggingface.co/blog/dpo-trl), a guide to using the TRL library's DPO method to fine tune Llama 2 on a specific dataset.
+- [Extended Guide: Instruction-tune Llama 2](https://www.philschmid.de/instruction-tune-llama-2), a guide to training Llama 2 to generate instructions from inputs, transforming the model from instruction-following to instruction-giving.
+- A [notebook](https://colab.research.google.com/drive/1SYpgFpcmtIUzdE7pxqknrM4ArCASfkFQ?usp=sharing) on how to fine-tune the Llama 2 model on a personal computer using QLoRa and TRL. 🌎
+
+⚡️ Inference
+- A [notebook](https://colab.research.google.com/drive/1TC56ArKerXUpbgRy5vM3woRsbTEVNq7h?usp=sharing) on how to quantize the Llama 2 model using GPTQ from the AutoGPTQ library. 🌎
+- A [notebook](https://colab.research.google.com/drive/1X1z9Q6domMKl2CnEM0QGHNwidLfR4dW2?usp=sharing) on how to run the Llama 2 Chat Model with 4-bit quantization on a local computer or Google Colab. 🌎
+
+🚀 Deploy
+- [Fine-tune LLaMA 2 (7-70B) on Amazon SageMaker](https://www.philschmid.de/sagemaker-llama2-qlora), a complete guide from setup to QLoRA fine-tuning and deployment on Amazon SageMaker.
+- [Deploy Llama 2 7B/13B/70B on Amazon SageMaker](https://www.philschmid.de/sagemaker-llama-llm), a guide on using Hugging Face's LLM DLC container for secure and scalable deployment.
+
+
+## LlamaConfig
+
+[[autodoc]] LlamaConfig
+
+
+## LlamaTokenizer
+
+[[autodoc]] LlamaTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## LlamaTokenizerFast
+
+[[autodoc]] LlamaTokenizerFast
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - update_post_processor
+ - save_vocabulary
+
+## LlamaModel
+
+[[autodoc]] LlamaModel
+ - forward
+
+
+## LlamaForCausalLM
+
+[[autodoc]] LlamaForCausalLM
+ - forward
+
+## LlamaForSequenceClassification
+
+[[autodoc]] LlamaForSequenceClassification
+ - forward
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llama3.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llama3.md
new file mode 100644
index 0000000000000000000000000000000000000000..9c77db44fcf308190e3d08d816c995ccf0634f57
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llama3.md
@@ -0,0 +1,82 @@
+
+
+# Llama3
+
+```py3
+import transformers
+import torch
+
+model_id = "meta-llama/Meta-Llama-3-8B"
+
+pipeline = transformers.pipeline("text-generation", model=model_id, model_kwargs={"torch_dtype": torch.bfloat16}, device_map="auto")
+pipeline("Hey how are you doing today?")
+```
+
+## Overview
+
+The Llama3 model was proposed in [Introducing Meta Llama 3: The most capable openly available LLM to date](https://ai.meta.com/blog/meta-llama-3/) by the meta AI team.
+
+The abstract from the blogpost is the following:
+
+*Today, we’re excited to share the first two models of the next generation of Llama, Meta Llama 3, available for broad use. This release features pretrained and instruction-fine-tuned language models with 8B and 70B parameters that can support a broad range of use cases. This next generation of Llama demonstrates state-of-the-art performance on a wide range of industry benchmarks and offers new capabilities, including improved reasoning. We believe these are the best open source models of their class, period. In support of our longstanding open approach, we’re putting Llama 3 in the hands of the community. We want to kickstart the next wave of innovation in AI across the stack—from applications to developer tools to evals to inference optimizations and more. We can’t wait to see what you build and look forward to your feedback.*
+
+Checkout all Llama3 model checkpoints [here](https://huggingface.co/models?search=llama3).
+The original code of the authors can be found [here](https://github.com/meta-llama/llama3).
+
+## Usage tips
+
+
+
+The `Llama3` models were trained using `bfloat16`, but the original inference uses `float16`. The checkpoints uploaded on the Hub use `torch_dtype = 'float16'`, which will be
+used by the `AutoModel` API to cast the checkpoints from `torch.float32` to `torch.float16`.
+
+The `dtype` of the online weights is mostly irrelevant unless you are using `torch_dtype="auto"` when initializing a model using `model = AutoModelForCausalLM.from_pretrained("path", torch_dtype = "auto")`. The reason is that the model will first be downloaded ( using the `dtype` of the checkpoints online), then it will be casted to the default `dtype` of `torch` (becomes `torch.float32`), and finally, if there is a `torch_dtype` provided in the config, it will be used.
+
+Training the model in `float16` is not recommended and is known to produce `nan`; as such, the model should be trained in `bfloat16`.
+
+
+
+Tips:
+
+- Weights for the Llama3 models can be obtained by filling out [this form](https://ai.meta.com/resources/models-and-libraries/llama-downloads/)
+- The architecture is exactly the same as Llama2.
+- The tokenizer is a BPE model based on [tiktoken](https://github.com/openai/tiktoken) (vs the one based on sentencepiece implementation for Llama2). The main difference that it ignores BPE merge rules when an input token is part of the vocab. This means that if no merge exist to produce `"hugging"`, instead of having the smallest units, like `["hug","ging"] form 2 tokens, if `"hugging"` is part of the vocab, it will be automatically returned as a token.
+- The original model uses `pad_id = -1` which means that there is no padding token. We can't have the same logic, make sure to add a padding token using `tokenizer.add_special_tokens({"pad_token":""})` and resize the token embedding accordingly. You should also set the `model.config.pad_token_id`. The `embed_tokens` layer of the model is initialized with `self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.config.padding_idx)`, which makes sure that encoding the padding token will output zeros, so passing it when initializing is recommended.
+- The original checkpoint can be converted using the [conversion script](https://github.com/huggingface/transformers/blob/main/src/transformers/models/llama/convert_llama_weights_to_hf.py). The script can be called with the following (example) command:
+
+ ```bash
+ python src/transformers/models/llama/convert_llama_weights_to_hf.py \
+ --input_dir /path/to/downloaded/llama/weights --model_size 7B --output_dir /output/path --llama_version 3
+ ```
+
+- After conversion, the model and tokenizer can be loaded via:
+
+ ```python
+ from transformers import AutoModelForCausalLM, AutoTokenizer
+
+ tokenizer = AutoTokenizer.from_pretrained("/output/path")
+ model = AutoModelForCausalLM.from_pretrained("/output/path")
+ ```
+
+ Note that executing the script requires enough CPU RAM to host the whole model in float16 precision (even if the biggest versions
+ come in several checkpoints they each contain a part of each weight of the model, so we need to load them all in RAM). For the 75B model, it's thus 145GB of RAM needed.
+
+- When using Flash Attention 2 via `attn_implementation="flash_attention_2"`, don't pass `torch_dtype` to the `from_pretrained` class method and use Automatic Mixed-Precision training. When using `Trainer`, it is simply specifying either `fp16` or `bf16` to `True`. Otherwise, make sure you are using `torch.autocast`. This is required because the Flash Attention only support `fp16` and `bf16` data type.
+
+## Resources
+
+A ton of cool resources are already available on the documentation page of [Llama2](./llama2), inviting contributors to add new resources curated for Llama3 here! 🤗
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llava.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llava.md
new file mode 100644
index 0000000000000000000000000000000000000000..e883572995e9243c72d20b8ead8b9fd2581b8549
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llava.md
@@ -0,0 +1,190 @@
+
+
+# LLaVa
+
+## Overview
+
+LLaVa is an open-source chatbot trained by fine-tuning LlamA/Vicuna on GPT-generated multimodal instruction-following data. It is an auto-regressive language model, based on the transformer architecture. In other words, it is an multi-modal version of LLMs fine-tuned for chat / instructions.
+
+The LLaVa model was proposed in [Visual Instruction Tuning](https://arxiv.org/abs/2304.08485) and improved in [Improved Baselines with Visual Instruction Tuning](https://arxiv.org/pdf/2310.03744) by Haotian Liu, Chunyuan Li, Yuheng Li and Yong Jae Lee.
+
+The abstract from the paper is the following:
+
+*Large multimodal models (LMM) have recently shown encouraging progress with visual instruction tuning. In this note, we show that the fully-connected vision-language cross-modal connector in LLaVA is surprisingly powerful and data-efficient. With simple modifications to LLaVA, namely, using CLIP-ViT-L-336px with an MLP projection and adding academic-task-oriented VQA data with simple response formatting prompts, we establish stronger baselines that achieve state-of-the-art across 11 benchmarks. Our final 13B checkpoint uses merely 1.2M publicly available data, and finishes full training in ∼1 day on a single 8-A100 node. We hope this can make state-of-the-art LMM research more accessible. Code and model will be publicly available*
+
+
+
+ LLaVa architecture. Taken from the original paper.
+
+This model was contributed by [ArthurZ](https://huggingface.co/ArthurZ) and [ybelkada](https://huggingface.co/ybelkada).
+The original code can be found [here](https://github.com/haotian-liu/LLaVA/tree/main/llava).
+
+## Usage tips
+
+- We advise users to use `padding_side="left"` when computing batched generation as it leads to more accurate results. Simply make sure to call `processor.tokenizer.padding_side = "left"` before generating.
+
+- Note the model has not been explicitly trained to process multiple images in the same prompt, although this is technically possible, you may experience inaccurate results.
+
+
+> [!NOTE]
+> LLaVA models after release v4.46 will raise warnings about adding `processor.patch_size = {{patch_size}}`, `processor.num_additional_image_tokens = {{num_additional_image_tokens}}` and processor.vision_feature_select_strategy = {{vision_feature_select_strategy}}`. It is strongly recommended to add the attributes to the processor if you own the model checkpoint, or open a PR if it is not owned by you.
+Adding these attributes means that LLaVA will try to infer the number of image tokens required per image and expand the text with as many `` placeholders as there will be tokens. Usually it is around 500 tokens per image, so make sure that the text is not truncated as otherwise there will be failure when merging the embeddings.
+The attributes can be obtained from model config, as `model.config.vision_config.patch_size` or `model.config.vision_feature_select_strategy`. The `num_additional_image_tokens` should be `1` if the vision backbone adds a CLS token or `0` if nothing extra is added to the vision patches.
+
+
+### Single image inference
+
+For best results, we recommend users to use the processor's `apply_chat_template()` method to format your prompt correctly. For that you need to construct a conversation history, passing in a plain string will not format your prompt. Each message in the conversation history for chat templates is a dictionary with keys "role" and "content". The "content" should be a list of dictionaries, for "text" and "image" modalities, as follows:
+
+```python
+from transformers import AutoProcessor
+
+processor = AutoProcessor.from_pretrained("llava-hf/llava-1.5-7b-hf")
+
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What’s shown in this image?"},
+ ],
+ },
+ {
+ "role": "assistant",
+ "content": [{"type": "text", "text": "This image shows a red stop sign."},]
+ },
+ {
+
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Describe the image in more details."},
+ ],
+ },
+]
+
+text_prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+
+# Note that the template simply formats your prompt, you still have to tokenize it and obtain pixel values for your images
+print(text_prompt)
+>>> "USER: \nUSER: Describe the image in more details. ASSISTANT:"
+```
+
+### Batched inference
+
+LLaVa also supports batched inference. Here is how you can do it:
+
+```python
+import requests
+from PIL import Image
+import torch
+from transformers import AutoProcessor, LlavaForConditionalGeneration
+
+# Load the model in half-precision
+model = LlavaForConditionalGeneration.from_pretrained("llava-hf/llava-1.5-7b-hf", torch_dtype=torch.float16, device_map="auto")
+processor = AutoProcessor.from_pretrained("llava-hf/llava-1.5-7b-hf")
+
+# Get two different images
+url = "https://www.ilankelman.org/stopsigns/australia.jpg"
+image_stop = Image.open(requests.get(url, stream=True).raw)
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image_cats = Image.open(requests.get(url, stream=True).raw)
+
+# Prepare a batch of two prompts
+conversation_1 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+]
+
+conversation_2 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+]
+
+prompt_1 = processor.apply_chat_template(conversation_1, add_generation_prompt=True)
+prompt_2 = processor.apply_chat_template(conversation_2, add_generation_prompt=True)
+prompts = [prompt_1, prompt_2]
+
+# We can simply feed images in the order they have to be used in the text prompt
+inputs = processor(images=[image_stop, image_cats], text=prompts, padding=True, return_tensors="pt").to(model.device, torch.float16)
+
+# Generate
+generate_ids = model.generate(**inputs, max_new_tokens=30)
+processor.batch_decode(generate_ids, skip_special_tokens=True)
+```
+
+- If you want to construct a chat prompt yourself, below is a list of prompt formats accepted by each llava checkpoint:
+
+[llava-interleave models](https://huggingface.co/collections/llava-hf/llava-interleave-668e19a97da0036aad4a2f19) requires the following format:
+```bash
+"<|im_start|>user \nWhat is shown in this image?<|im_end|><|im_start|>assistant"
+```
+
+For multiple turns conversation:
+
+```bash
+"<|im_start|>user \n<|im_end|><|im_start|>assistant <|im_end|><|im_start|>user \n<|im_end|><|im_start|>assistant "
+```
+
+[llava-1.5 models](https://huggingface.co/collections/llava-hf/llava-15-65f762d5b6941db5c2ba07e0) requires the following format:
+```bash
+"USER: \n ASSISTANT:"
+```
+
+For multiple turns conversation:
+
+```bash
+"USER: \n ASSISTANT: USER: ASSISTANT: USER: ASSISTANT:"
+```
+
+### Using Flash Attention 2
+
+Flash Attention 2 is an even faster, optimized version of the previous optimization, please refer to the [Flash Attention 2 section of performance docs](https://huggingface.co/docs/transformers/perf_infer_gpu_one).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with BEiT.
+
+
+
+- A [Google Colab demo](https://colab.research.google.com/drive/1qsl6cd2c8gGtEW1xV5io7S8NHh-Cp1TV?usp=sharing) on how to run Llava on a free-tier Google colab instance leveraging 4-bit inference.
+- A [similar notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LLaVa/Inference_with_LLaVa_for_multimodal_generation.ipynb) showcasing batched inference. 🌎
+
+
+## LlavaConfig
+
+[[autodoc]] LlavaConfig
+
+## LlavaProcessor
+
+[[autodoc]] LlavaProcessor
+
+## LlavaForConditionalGeneration
+
+[[autodoc]] LlavaForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llava_next.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llava_next.md
new file mode 100644
index 0000000000000000000000000000000000000000..88bd63e7101f1793dab78d3608e851c3de096ebd
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llava_next.md
@@ -0,0 +1,298 @@
+
+
+# LLaVA-NeXT
+
+## Overview
+
+The LLaVA-NeXT model was proposed in [LLaVA-NeXT: Improved reasoning, OCR, and world knowledge](https://llava-vl.github.io/blog/2024-01-30-llava-next/) by Haotian Liu, Chunyuan Li, Yuheng Li, Bo Li, Yuanhan Zhang, Sheng Shen, Yong Jae Lee. LLaVa-NeXT (also called LLaVa-1.6) improves upon [LLaVa](llava) by increasing the input image resolution and training on an improved visual instruction tuning dataset to improve OCR and common sense reasoning.
+
+The introduction from the blog is the following:
+
+*In October 2023, we released LLaVA-1.5 with a simple and efficient design along with great performance on a benchmark suite of 12 datasets. It has since served as the foundation of many comprehensive studies of data, model, and capabilities of large multimodal models (LMM), and has enabled various new applications.
+
+Today, we are thrilled to present LLaVA-NeXT, with improved reasoning, OCR, and world knowledge. LLaVA-NeXT even exceeds Gemini Pro on several benchmarks.
+
+Compared with LLaVA-1.5, LLaVA-NeXT has several improvements:
+
+Increasing the input image resolution to 4x more pixels. This allows it to grasp more visual details. It supports three aspect ratios, up to 672x672, 336x1344, 1344x336 resolution.
+Better visual reasoning and OCR capability with an improved visual instruction tuning data mixture.
+Better visual conversation for more scenarios, covering different applications. Better world knowledge and logical reasoning.
+Efficient deployment and inference with SGLang.
+Along with performance improvements, LLaVA-NeXT maintains the minimalist design and data efficiency of LLaVA-1.5. It re-uses the pretrained connector of LLaVA-1.5, and still uses less than 1M visual instruction tuning samples. The largest 34B variant finishes training in ~1 day with 32 A100s.*
+
+
+
+ LLaVa-NeXT incorporates a higher input resolution by encoding various patches of the input image. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/haotian-liu/LLaVA/tree/main).
+
+## Usage tips
+
+- We advise users to use `padding_side="left"` when computing batched generation as it leads to more accurate results. Simply make sure to call `processor.tokenizer.padding_side = "left"` before generating.
+
+
+
+- Llava-Next uses different number of patches for images and thus has to pad the inputs inside modeling code, aside from the padding done when processing the inputs. The default setting is "left-padding" if model is in `eval()` mode, otherwise "right-padding".
+
+
+
+
+> [!NOTE]
+> LLaVA models after release v4.46 will raise warnings about adding `processor.patch_size = {{patch_size}}`, `processor.num_additional_image_tokens = {{num_additional_image_tokens}}` and processor.vision_feature_select_strategy = {{vision_feature_select_strategy}}`. It is strongly recommended to add the attributes to the processor if you own the model checkpoint, or open a PR if it is not owned by you.
+Adding these attributes means that LLaVA will try to infer the number of image tokens required per image and expand the text with as many `` placeholders as there will be tokens. Usually it is around 500 tokens per image, so make sure that the text is not truncated as otherwise there will be failure when merging the embeddings.
+The attributes can be obtained from model config, as `model.config.vision_config.patch_size` or `model.config.vision_feature_select_strategy`. The `num_additional_image_tokens` should be `1` if the vision backbone adds a CLS token or `0` if nothing extra is added to the vision patches.
+
+
+- Note that each checkpoint has been trained with a specific prompt format, depending on which large language model (LLM) was used. You can use the processor's `apply_chat_template` to format your prompts correctly. For that you have to construct a conversation history, passing a plain string will not format your prompt. Each message in the conversation history for chat templates is a dictionary with keys "role" and "content". The "content" should be a list of dictionaries, for "text" and "image" modalities. Below is an example of how to do that and the list of formats accepted by each checkpoint.
+
+We will use [llava-v1.6-mistral-7b-hf](https://huggingface.co/llava-hf/llava-v1.6-mistral-7b-hf) and a conversation history of text and image. Each content field has to be a list of dicts, as follows:
+
+```python
+from transformers import LlavaNextProcessor
+
+processor = LlavaNextProcessor.from_pretrained("llava-hf/llava-v1.6-mistral-7b-hf")
+
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What’s shown in this image?"},
+ ],
+ },
+ {
+ "role": "assistant",
+ "content": [{"type": "text", "text": "This image shows a red stop sign."},]
+ },
+ {
+
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Describe the image in more details."},
+ ],
+ },
+]
+
+text_prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+
+# Note that the template simply formats your prompt, you still have to tokenize it and obtain pixel values for your images
+print(text_prompt)
+>>> "[INST] \nWhat's shown in this image? [/INST] This image shows a red stop sign. [INST] Describe the image in more details. [/INST]"
+```
+
+- If you want to construct a chat prompt yourself, below is a list of possible formats
+.
+[llava-v1.6-mistral-7b-hf](https://huggingface.co/llava-hf/llava-v1.6-mistral-7b-hf) requires the following format:
+```bash
+"[INST] \nWhat is shown in this image? [/INST]"
+```
+
+[llava-v1.6-vicuna-7b-hf](https://huggingface.co/llava-hf/llava-v1.6-vicuna-7b-hf) and [llava-v1.6-vicuna-13b-hf](https://huggingface.co/llava-hf/llava-v1.6-vicuna-13b-hf) require the following format:
+```bash
+"A chat between a curious human and an artificial intelligence assistant. The assistant gives helpful, detailed, and polite answers to the human's questions. USER: \nWhat is shown in this image? ASSISTANT:"
+```
+
+[llava-v1.6-34b-hf](https://huggingface.co/llava-hf/llava-v1.6-34b-hf) requires the following format:
+```bash
+"<|im_start|>system\nAnswer the questions.<|im_end|><|im_start|>user\n\nWhat is shown in this image?<|im_end|><|im_start|>assistant\n"
+```
+
+[llama3-llava-next-8b-hf](https://huggingface.co/llava-hf/llava-next-8b-hf) requires the following format:
+
+```bash
+"<|start_header_id|>system<|end_header_id|>\n\nYou are a helpful language and vision assistant. You are able to understand the visual content that the user provides, and assist the user with a variety of tasks using natural language.<|eot_id|><|start_header_id|><|start_header_id|>user<|end_header_id|>\n\n\nWhat is shown in this image?<|eot_id|><|start_header_id|>assistant<|end_header_id|>\n\n"
+```
+
+[llava-next-72b-hf](https://huggingface.co/llava-hf/llava-next-72b-hf) and [llava-next-110b-hf](https://huggingface.co/llava-hf/llava-next-110b-hf) require the following format:
+
+```bash
+"<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n<|im_start|>user\n\nWhat is shown in this image?<|im_end|>\n<|im_start|>assistant\n"
+```
+
+## Usage example
+
+### Single image inference
+
+Here's how to load the model and perform inference in half-precision (`torch.float16`):
+
+```python
+from transformers import LlavaNextProcessor, LlavaNextForConditionalGeneration
+import torch
+from PIL import Image
+import requests
+
+processor = LlavaNextProcessor.from_pretrained("llava-hf/llava-v1.6-mistral-7b-hf")
+
+model = LlavaNextForConditionalGeneration.from_pretrained("llava-hf/llava-v1.6-mistral-7b-hf", torch_dtype=torch.float16, low_cpu_mem_usage=True)
+model.to("cuda:0")
+
+# prepare image and text prompt, using the appropriate prompt template
+url = "https://github.com/haotian-liu/LLaVA/blob/1a91fc274d7c35a9b50b3cb29c4247ae5837ce39/images/llava_v1_5_radar.jpg?raw=true"
+image = Image.open(requests.get(url, stream=True).raw)
+
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+]
+prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+inputs = processor(image, prompt, return_tensors="pt").to("cuda:0")
+
+# autoregressively complete prompt
+output = model.generate(**inputs, max_new_tokens=100)
+
+print(processor.decode(output[0], skip_special_tokens=True))
+```
+
+### Multi image inference
+
+LLaVa-Next can perform inference with multiple images as input, where images either belong to the same prompt or different prompts (in batched inference). Here is how you can do it:
+
+```python
+import requests
+from PIL import Image
+import torch
+from transformers import AutoProcessor, AutoModelForImageTextToText
+
+# Load the model in half-precision
+model = AutoModelForImageTextToText.from_pretrained("llava-hf/llava-v1.6-mistral-7b-hf", torch_dtype=torch.float16, device_map="auto")
+processor = AutoProcessor.from_pretrained("llava-hf/llava-v1.6-mistral-7b-hf")
+
+# Get three different images
+url = "https://www.ilankelman.org/stopsigns/australia.jpg"
+image_stop = Image.open(requests.get(url, stream=True).raw)
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image_cats = Image.open(requests.get(url, stream=True).raw)
+
+url = "https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/snowman.jpg"
+image_snowman = Image.open(requests.get(url, stream=True).raw)
+
+# Prepare a batch of two prompts, where the first one is a multi-turn conversation and the second is not
+conversation_1 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+ {
+ "role": "assistant",
+ "content": [
+ {"type": "text", "text": "There is a red stop sign in the image."},
+ ],
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What about this image? How many cats do you see?"},
+ ],
+ },
+]
+
+conversation_2 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+]
+
+prompt_1 = processor.apply_chat_template(conversation_1, add_generation_prompt=True)
+prompt_2 = processor.apply_chat_template(conversation_2, add_generation_prompt=True)
+prompts = [prompt_1, prompt_2]
+
+# We can simply feed images in the order they have to be used in the text prompt
+# Each "" token uses one image leaving the next for the subsequent "" tokens
+inputs = processor(images=[image_stop, image_cats, image_snowman], text=prompts, padding=True, return_tensors="pt").to(model.device)
+
+# Generate
+generate_ids = model.generate(**inputs, max_new_tokens=30)
+processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)
+```
+
+## Model optimization
+
+### Quantization using Bitsandbytes
+
+The model can be loaded in 8 or 4 bits, greatly reducing the memory requirements while maintaining the performance of the original model. First make sure to install bitsandbytes, `pip install bitsandbytes`, and to have access to a GPU/accelerator that is supported by the library.
+
+
+
+bitsandbytes is being refactored to support multiple backends beyond CUDA. Currently, ROCm (AMD GPU) and Intel CPU implementations are mature, with Intel XPU in progress and Apple Silicon support expected by Q4/Q1. For installation instructions and the latest backend updates, visit [this link](https://huggingface.co/docs/bitsandbytes/main/en/installation#multi-backend).
+
+We value your feedback to help identify bugs before the full release! Check out [these docs](https://huggingface.co/docs/bitsandbytes/main/en/non_cuda_backends) for more details and feedback links.
+
+
+
+Simply change the snippet above with:
+
+```python
+from transformers import AutoModelForImageTextToText, BitsAndBytesConfig
+
+# specify how to quantize the model
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_compute_dtype=torch.float16,
+)
+
+model = AutoModelForImageTextToText.from_pretrained("llava-hf/llava-v1.6-mistral-7b-hf", quantization_config=quantization_config, device_map="auto")
+```
+
+### Use Flash-Attention 2 to further speed-up generation
+
+First make sure to install flash-attn. Refer to the [original repository of Flash Attention](https://github.com/Dao-AILab/flash-attention) regarding that package installation. Simply change the snippet above with:
+
+```python
+from transformers import AutoModelForImageTextToText
+
+model = AutoModelForImageTextToText.from_pretrained(
+ model_id,
+ torch_dtype=torch.float16,
+ low_cpu_mem_usage=True,
+ use_flash_attention_2=True
+).to(0)
+```
+
+## LlavaNextConfig
+
+[[autodoc]] LlavaNextConfig
+
+## LlavaNextImageProcessor
+
+[[autodoc]] LlavaNextImageProcessor
+ - preprocess
+
+## LlavaNextProcessor
+
+[[autodoc]] LlavaNextProcessor
+
+## LlavaNextForConditionalGeneration
+
+[[autodoc]] LlavaNextForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llava_next_video.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llava_next_video.md
new file mode 100644
index 0000000000000000000000000000000000000000..cc3a61aae6c736d21070ab2ec172cda7ad9b392b
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llava_next_video.md
@@ -0,0 +1,282 @@
+
+
+# LLaVa-NeXT-Video
+
+## Overview
+
+The LLaVa-NeXT-Video model was proposed in [LLaVA-NeXT: A Strong Zero-shot Video Understanding Model
+](https://llava-vl.github.io/blog/2024-04-30-llava-next-video/) by Yuanhan Zhang, Bo Li, Haotian Liu, Yong Jae Lee, Liangke Gui, Di Fu, Jiashi Feng, Ziwei Liu, Chunyuan Li. LLaVa-NeXT-Video improves upon [LLaVa-NeXT](llava_next) by fine-tuning on a mix if video and image dataset thus increasing the model's performance on videos.
+
+[LLaVA-NeXT](llava_next) surprisingly has strong performance in understanding video content in zero-shot fashion with the AnyRes technique that it uses. The AnyRes technique naturally represents a high-resolution image into multiple images. This technique is naturally generalizable to represent videos because videos can be considered as a set of frames (similar to a set of images in LLaVa-NeXT). The current version of LLaVA-NeXT makes use of AnyRes and trains with supervised fine-tuning (SFT) on top of LLaVA-Next on video data to achieves better video understanding capabilities.The model is a current SOTA among open-source models on [VideoMME bench](https://arxiv.org/abs/2405.21075).
+
+
+The introduction from the blog is the following:
+
+On January 30, 2024, we released LLaVA-NeXT, an open-source Large Multimodal Model (LMM) that has been trained exclusively on text-image data. With the proposed AnyRes technique, it boosts capabilities in reasoning, OCR, and world knowledge, demonstrating remarkable performance across a spectrum of image-based multimodal understanding tasks, and even exceeding Gemini-Pro on several image benchmarks, e.g. MMMU and MathVista.
+
+**In today’s exploration, we delve into the performance of LLaVA-NeXT within the realm of video understanding tasks. We reveal that LLaVA-NeXT surprisingly has strong performance in understanding video content. The current version of LLaVA-NeXT for videos has several improvements:
+
+- Zero-shot video representation capabilities with AnyRes: The AnyRes technique naturally represents a high-resolution image into multiple images that a pre-trained VIT is able to digest, and forms them into a concantenated sequence. This technique is naturally generalizable to represent videos (consisting of multiple frames), allowing the image-only-trained LLaVA-Next model to perform surprisingly well on video tasks. Notably, this is the first time that LMMs show strong zero-shot modality transfer ability.
+- Inference with length generalization improves on longer videos. The linear scaling technique enables length generalization, allowing LLaVA-NeXT to effectively handle long-video beyond the limitation of the "max_token_length" of the LLM.
+- Strong video understanding ability. (1) LLaVA-Next-Image, which combines the above two techniques, yields superior zero-shot performance than open-source LMMs tuned on videos. (2) LLaVA-Next-Video, further supervised fine-tuning (SFT) LLaVA-Next-Image on video data, achieves better video understanding capabilities compared to LLaVA-Next-Image. (3) LLaVA-Next-Video-DPO, which aligns the model response with AI feedback using direct preference optimization (DPO), showing significant performance boost.
+- Efficient deployment and inference with SGLang. It allows 5x faster inference on video tasks, allowing more scalable serving such as million-level video re-captioning. See instructions in our repo.**
+
+
+This model was contributed by [RaushanTurganbay](https://huggingface.co/RaushanTurganbay).
+The original code can be found [here](https://github.com/LLaVA-VL/LLaVA-NeXT/tree/inference).
+
+## Usage tips
+
+- We advise users to use `padding_side="left"` when computing batched generation as it leads to more accurate results. Simply make sure to call `processor.tokenizer.padding_side = "left"` before generating.
+
+
+
+- Llava-Next uses different number of patches for images and thus has to pad the inputs inside modeling code, aside from the padding done when processing the inputs. The default setting is "left-padding" if model is in `eval()` mode, otherwise "right-padding".
+
+
+
+
+> [!NOTE]
+> LLaVA models after release v4.46 will raise warnings about adding `processor.patch_size = {{patch_size}}`, `processor.num_additional_image_tokens = {{num_additional_image_tokens}}` and processor.vision_feature_select_strategy = {{vision_feature_select_strategy}}`. It is strongly recommended to add the attributes to the processor if you own the model checkpoint, or open a PR if it is not owned by you.
+Adding these attributes means that LLaVA will try to infer the number of image tokens required per image and expand the text with as many `` placeholders as there will be tokens. Usually it is around 500 tokens per image, so make sure that the text is not truncated as otherwise there will be failure when merging the embeddings.
+The attributes can be obtained from model config, as `model.config.vision_config.patch_size` or `model.config.vision_feature_select_strategy`. The `num_additional_image_tokens` should be `1` if the vision backbone adds a CLS token or `0` if nothing extra is added to the vision patches.
+
+
+- Note that each checkpoint has been trained with a specific prompt format, depending on which large language model (LLM) was used. You can use tokenizer's `apply_chat_template` to format your prompts correctly. Below is an example of how to do that.
+
+We will use [LLaVA-NeXT-Video-7B-hf](https://huggingface.co/llava-hf/LLaVA-NeXT-Video-7B-hf) and a conversation history of videos and images. Each content field has to be a list of dicts, as follows:
+
+```python
+from transformers import LlavaNextVideoProcessor
+
+processor = LlavaNextVideoProcessor.from_pretrained("llava-hf/LLaVA-NeXT-Video-7B-hf")
+
+conversation = [
+ {
+ "role": "system",
+ "content": [
+ {"type": "text", "text": "A chat between a curious human and an artificial intelligence assistant. The assistant gives helpful, detailed, and polite answers to the human's questions."},
+ ],
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "What’s shown in this image?"},
+ {"type": "image"},
+ ],
+ },
+ {
+ "role": "assistant",
+ "content": [{"type": "text", "text": "This image shows a red stop sign."},]
+ },
+ {
+
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Why is this video funny?"},
+ {"type": "video"},
+ ],
+ },
+]
+
+text_prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+
+# Note that the template simply formats your prompt, you still have to tokenize it and obtain pixel values for your visuals
+print(text_prompt)
+```
+
+## Usage example
+
+### Single Media Mode
+
+The model can accept both images and videos as input. Here's an example code for inference in half-precision (`torch.float16`):
+
+```python
+import av
+import torch
+import numpy as np
+from transformers import LlavaNextVideoForConditionalGeneration, LlavaNextVideoProcessor
+
+def read_video_pyav(container, indices):
+ '''
+ Decode the video with PyAV decoder.
+ Args:
+ container (`av.container.input.InputContainer`): PyAV container.
+ indices (`List[int]`): List of frame indices to decode.
+ Returns:
+ result (np.ndarray): np array of decoded frames of shape (num_frames, height, width, 3).
+ '''
+ frames = []
+ container.seek(0)
+ start_index = indices[0]
+ end_index = indices[-1]
+ for i, frame in enumerate(container.decode(video=0)):
+ if i > end_index:
+ break
+ if i >= start_index and i in indices:
+ frames.append(frame)
+ return np.stack([x.to_ndarray(format="rgb24") for x in frames])
+
+# Load the model in half-precision
+model = LlavaNextVideoForConditionalGeneration.from_pretrained("llava-hf/LLaVA-NeXT-Video-7B-hf", torch_dtype=torch.float16, device_map="auto")
+processor = LlavaNextVideoProcessor.from_pretrained("llava-hf/LLaVA-NeXT-Video-7B-hf")
+
+# Load the video as an np.array, sampling uniformly 8 frames (can sample more for longer videos)
+video_path = hf_hub_download(repo_id="raushan-testing-hf/videos-test", filename="sample_demo_1.mp4", repo_type="dataset")
+container = av.open(video_path)
+total_frames = container.streams.video[0].frames
+indices = np.arange(0, total_frames, total_frames / 8).astype(int)
+video = read_video_pyav(container, indices)
+
+conversation = [
+ {
+
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Why is this video funny?"},
+ {"type": "video"},
+ ],
+ },
+]
+
+prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+inputs = processor(text=prompt, videos=video, return_tensors="pt")
+
+out = model.generate(**inputs, max_new_tokens=60)
+processor.batch_decode(out, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+```
+
+
+### Mixed Media Mode
+
+The model can also generate from an interleaved image-video inputs. However note, that it was not trained in interleaved image-video setting which might affect the performance. Below is an example usage for mixed media input, add the following lines to the above code snippet:
+
+```python
+from PIL import Image
+import requests
+
+# Generate from image and video mixed inputs
+# Load and image and write a new prompt
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+conversation = [
+ {
+
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "How many cats are there in the image?"},
+ {"type": "image"},
+ ],
+ },
+ {
+
+ "role": "assistant",
+ "content": [{"type": "text", "text": "There are two cats"}],
+ },
+ {
+
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Why is this video funny?"},
+ {"type": "video"},
+ ],
+ },
+]
+prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+inputs = processor(text=prompt, images=image, videos=clip, padding=True, return_tensors="pt")
+
+# Generate
+generate_ids = model.generate(**inputs, max_length=50)
+processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+
+```
+
+## Model optimization
+
+### Quantization using Bitsandbytes for memory efficiency
+
+The model can be loaded in lower bits, significantly reducing memory burden while maintaining the performance of the original model. This allows for efficient deployment on resource-constrained cases.
+
+First, make sure to install bitsandbytes by running `pip install bitsandbytes` and to have access to a GPU/accelerator that is supported by the library.
+
+
+
+bitsandbytes is being refactored to support multiple backends beyond CUDA. Currently, ROCm (AMD GPU) and Intel CPU implementations are mature, with Intel XPU in progress and Apple Silicon support expected by Q4/Q1. For installation instructions and the latest backend updates, visit [this link](https://huggingface.co/docs/bitsandbytes/main/en/installation#multi-backend).
+
+We value your feedback to help identify bugs before the full release! Check out [these docs](https://huggingface.co/docs/bitsandbytes/main/en/non_cuda_backends) for more details and feedback links.
+
+
+
+Then simply load the quantized model by adding [`BitsAndBytesConfig`](../main_classes/quantization#transformers.BitsAndBytesConfig) as shown below:
+
+
+```python
+from transformers import LlavaNextVideoForConditionalGeneration, LlavaNextVideoProcessor
+
+# specify how to quantize the model
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_compute_dtype=torch.float16,
+)
+
+model = LlavaNextVideoForConditionalGeneration.from_pretrained("llava-hf/LLaVA-NeXT-Video-7B-hf", quantization_config=quantization_config, device_map="auto")
+```
+
+
+### Flash-Attention 2 to speed-up generation
+
+Additionally, we can greatly speed-up model inference by using [Flash Attention](../perf_train_gpu_one#flash-attention-2), which is a faster implementation of the attention mechanism used inside the model.
+
+First, make sure to install the latest version of Flash Attention 2:
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Also, you should have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of the [flash attention repository](https://github.com/Dao-AILab/flash-attention). FlashAttention-2 can only be used when a model is loaded in `torch.float16` or `torch.bfloat16`.
+
+To load and run a model using Flash Attention-2, simply add `attn_implementation="flash_attention_2"` when loading the model as follows:
+
+```python
+from transformers import LlavaNextVideoForConditionalGeneration
+
+model = LlavaNextVideoForConditionalGeneration.from_pretrained(
+ "llava-hf/LLaVA-NeXT-Video-7B-hf",
+ torch_dtype=torch.float16,
+ attn_implementation="flash_attention_2",
+).to(0)
+```
+
+
+
+## LlavaNextVideoConfig
+
+[[autodoc]] LlavaNextVideoConfig
+
+## LlavaNextVideoProcessor
+
+[[autodoc]] LlavaNextVideoProcessor
+
+## LlavaNextVideoImageProcessor
+
+[[autodoc]] LlavaNextVideoImageProcessor
+
+## LlavaNextVideoForConditionalGeneration
+
+[[autodoc]] LlavaNextVideoForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llava_onevision.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llava_onevision.md
new file mode 100644
index 0000000000000000000000000000000000000000..b6b0a2bfa1d123f968a8725b72efdb988937024f
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llava_onevision.md
@@ -0,0 +1,328 @@
+
+
+# LLaVA-OneVision
+
+## Overview
+
+The LLaVA-OneVision model was proposed in [LLaVA-OneVision: Easy Visual Task Transfer](https://arxiv.org/abs/2408.03326) by
+
+ LLaVA-OneVision architecture. Taken from the original paper.
+
+Tips:
+
+- We advise users to use `padding_side="left"` when computing batched generation as it leads to more accurate results. Simply make sure to call `processor.tokenizer.padding_side = "left"` before generating.
+
+
+
+- Llava-OneVision uses different number of patches for images and thus has to pad the inputs inside modeling code, aside from the padding done when processing the inputs. The default setting is "left-padding" if model is in `eval()` mode, otherwise "right-padding".
+
+
+
+- Note that the model should use a specific prompt format, on which the large language model (LLM) was trained. You can use the processor's `apply_chat_template` to format your prompts correctly. For that you have to construct a conversation history, passing a plain string will not format your prompt. Each message in the conversation history for chat templates is a dictionary with keys "role" and "content". The "content" should be a list of dictionaries, for "text" and "image" modalities.
+
+We will use [llava-onevision-qwen2-7b-si-hf](https://huggingface.co/llava-hf/llava-onevision-qwen2-7b-si-hf) and a conversation history of text and image. Each content field has to be a list of dicts, as follows:
+
+```python
+from transformers import AutoProcessor
+
+processor = AutoProcessor.from_pretrained("llava-hf/llava-onevision-qwen2-7b-si-hf")
+
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What’s shown in this image?"},
+ ],
+ },
+ {
+ "role": "assistant",
+ "content": [{"type": "text", "text": "This image shows a red stop sign."},]
+ },
+ {
+
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Describe the image in more details."},
+ ],
+ },
+]
+
+text_prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+
+# Note that the template simply formats your prompt, you still have to tokenize it and obtain pixel values for your images
+print(text_prompt)
+>>> "<|im_start|>user\nWhat is shown in this image?<|im_end|>\n<|im_start|>assistant\nPage showing the list of options.<|im_end|>"
+```
+
+This model was contributed by [RaushanTurganbay](https://huggingface.co/RaushanTurganbay).
+The original code can be found [here](https://github.com/LLaVA-VL/LLaVA-NeXT/tree/main).
+
+
+## Usage example
+
+### Single image inference
+
+Here's how to load the model and perform inference in half-precision (`torch.float16`):
+
+```python
+from transformers import AutoProcessor, LlavaOnevisionForConditionalGeneration
+import torch
+from PIL import Image
+import requests
+
+processor = AutoProcessor.from_pretrained("llava-hf/llava-onevision-qwen2-7b-ov-hf")
+model = LlavaOnevisionForConditionalGeneration.from_pretrained("llava-hf/llava-onevision-qwen2-7b-ov-hf", torch_dtype=torch.float16, low_cpu_mem_usage=True)
+model.to("cuda:0")
+
+# prepare image and text prompt, using the appropriate prompt template
+url = "https://github.com/haotian-liu/LLaVA/blob/1a91fc274d7c35a9b50b3cb29c4247ae5837ce39/images/llava_v1_5_radar.jpg?raw=true"
+image = Image.open(requests.get(url, stream=True).raw)
+
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+]
+prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+inputs = processor(images=image, text=prompt, return_tensors="pt").to("cuda:0", torch.float16)
+
+# autoregressively complete prompt
+output = model.generate(**inputs, max_new_tokens=100)
+print(processor.decode(output[0], skip_special_tokens=True))
+'user\n\nWhat is shown in this image?\nassistant\nThe image shows a radar chart, also known as a spider chart or a star chart, which is used to compare multiple quantitative variables. Each axis represents a different variable, and the chart is filled with'
+```
+
+### Multi image inference
+
+LLaVa-OneVision can perform inference with multiple images as input, where images either belong to the same prompt or different prompts (in batched inference). For that you have to use checkpoints with an "ov" suffix. Here is how you can do it:
+
+```python
+import requests
+from PIL import Image
+import torch
+from transformers import AutoProcessor, LlavaOnevisionForConditionalGeneration
+
+# Load the model in half-precision
+model = LlavaOnevisionForConditionalGeneration.from_pretrained("llava-hf/llava-onevision-qwen2-7b-ov-hf", torch_dtype=torch.float16, device_map="auto")
+processor = AutoProcessor.from_pretrained("llava-hf/llava-onevision-qwen2-7b-ov-hf")
+
+# Get three different images
+url = "https://www.ilankelman.org/stopsigns/australia.jpg"
+image_stop = Image.open(requests.get(url, stream=True).raw)
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image_cats = Image.open(requests.get(url, stream=True).raw)
+
+url = "https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/snowman.jpg"
+image_snowman = Image.open(requests.get(url, stream=True).raw)
+
+# Prepare a batch of two prompts, where the first one is a multi-turn conversation and the second is not
+conversation_1 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+ {
+ "role": "assistant",
+ "content": [
+ {"type": "text", "text": "There is a red stop sign in the image."},
+ ],
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What about this image? How many cats do you see?"},
+ ],
+ },
+]
+
+conversation_2 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+]
+
+prompt_1 = processor.apply_chat_template(conversation_1, add_generation_prompt=True)
+prompt_2 = processor.apply_chat_template(conversation_2, add_generation_prompt=True)
+prompts = [prompt_1, prompt_2]
+
+# We can simply feed images in the order they have to be used in the text prompt
+inputs = processor(images=[image_stop, image_cats, image_snowman], text=prompts, padding=True, return_tensors="pt").to(model.device, torch.float16)
+
+# Generate
+generate_ids = model.generate(**inputs, max_new_tokens=30)
+processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)
+['user\n\nWhat is shown in this image?\nassistant\nThere is a red stop sign in the image.\nuser\n\nWhat about this image? How many cats do you see?\nassistant\ntwo', 'user\n\nWhat is shown in this image?\nassistant\n']
+```
+
+### Video inference
+
+LLaVa-OneVision also can perform inference with videos as input, where video frames are treated as multiple images. Here is how you can do it:
+
+```python
+import av
+import numpy as np
+from huggingface_hub import hf_hub_download
+
+import torch
+from transformers import AutoProcessor, LlavaOnevisionForConditionalGeneration
+
+# Load the model in half-precision
+model = LlavaOnevisionForConditionalGeneration.from_pretrained("llava-hf/llava-onevision-qwen2-7b-ov-hf", torch_dtype=torch.float16, device_map="auto")
+processor = AutoProcessor.from_pretrained("llava-hf/llava-onevision-qwen2-7b-ov-hf")
+
+
+def read_video_pyav(container, indices):
+ '''
+ Decode the video with PyAV decoder.
+ Args:
+ container (`av.container.input.InputContainer`): PyAV container.
+ indices (`List[int]`): List of frame indices to decode.
+ Returns:
+ result (np.ndarray): np array of decoded frames of shape (num_frames, height, width, 3).
+ '''
+ frames = []
+ container.seek(0)
+ start_index = indices[0]
+ end_index = indices[-1]
+ for i, frame in enumerate(container.decode(video=0)):
+ if i > end_index:
+ break
+ if i >= start_index and i in indices:
+ frames.append(frame)
+ return np.stack([x.to_ndarray(format="rgb24") for x in frames])
+
+# Load the video as an np.array, sampling uniformly 8 frames (can sample more for longer videos, up to 32 frames)
+video_path = hf_hub_download(repo_id="raushan-testing-hf/videos-test", filename="sample_demo_1.mp4", repo_type="dataset")
+container = av.open(video_path)
+total_frames = container.streams.video[0].frames
+indices = np.arange(0, total_frames, total_frames / 8).astype(int)
+video = read_video_pyav(container, indices)
+
+# For videos we have to feed a "video" type instead of "image"
+conversation = [
+ {
+
+ "role": "user",
+ "content": [
+ {"type": "video"},
+ {"type": "text", "text": "Why is this video funny?"},
+ ],
+ },
+]
+
+prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+inputs = processor(videos=list(video), text=prompt, return_tensors="pt").to("cuda:0", torch.float16)
+
+out = model.generate(**inputs, max_new_tokens=60)
+processor.batch_decode(out, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+["user\n\nWhy is this video funny?\nassistant\nThe video appears to be humorous because it shows a young child, who is wearing glasses and holding a book, seemingly reading with a serious and focused expression. The child's glasses are a bit oversized for their face, which adds a comical touch, as it's a common trope to see children wearing"]
+```
+
+## Model optimization
+
+### Quantization using bitsandbytes
+
+The model can be loaded in 8 or 4 bits, greatly reducing the memory requirements while maintaining the performance of the original model. First make sure to install bitsandbytes, `pip install bitsandbytes` and make sure to have access to a GPU/accelerator that is supported by the library.
+
+
+
+bitsandbytes is being refactored to support multiple backends beyond CUDA. Currently, ROCm (AMD GPU) and Intel CPU implementations are mature, with Intel XPU in progress and Apple Silicon support expected by Q4/Q1. For installation instructions and the latest backend updates, visit [this link](https://huggingface.co/docs/bitsandbytes/main/en/installation#multi-backend).
+
+We value your feedback to help identify bugs before the full release! Check out [these docs](https://huggingface.co/docs/bitsandbytes/main/en/non_cuda_backends) for more details and feedback links.
+
+
+
+Simply change the snippet above with:
+
+```python
+from transformers import LlavaOnevisionForConditionalGeneration, BitsAndBytesConfig
+
+# specify how to quantize the model
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_compute_dtype=torch.float16,
+)
+
+model = LlavaOnevisionForConditionalGeneration.from_pretrained(model_id, quantization_config=quantization_config, device_map="auto")
+```
+
+### Use Flash-Attention 2 to further speed-up generation
+
+First make sure to install flash-attn. Refer to the [original repository of Flash Attention](https://github.com/Dao-AILab/flash-attention) regarding that package installation. Simply change the snippet above with:
+
+```python
+from transformers import LlavaOnevisionForConditionalGeneration
+
+model = LlavaOnevisionForConditionalGeneration.from_pretrained(
+ model_id,
+ torch_dtype=torch.float16,
+ low_cpu_mem_usage=True,
+ use_flash_attention_2=True
+).to(0)
+```
+
+
+## LlavaOnevisionConfig
+
+[[autodoc]] LlavaOnevisionConfig
+
+## LlavaOnevisionProcessor
+
+[[autodoc]] LlavaOnevisionProcessor
+
+## LlavaOnevisionImageProcessor
+
+[[autodoc]] LlavaOnevisionImageProcessor
+
+## LlavaOnevisionVideoProcessor
+
+[[autodoc]] LlavaOnevisionVideoProcessor
+
+## LlavaOnevisionForConditionalGeneration
+
+[[autodoc]] LlavaOnevisionForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/longformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/longformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..20ba7a922515ddc3b249b4a5d6a00004cd01712f
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/longformer.md
@@ -0,0 +1,213 @@
+
+
+# Longformer
+
+
+
+## Overview
+
+The Longformer model was presented in [Longformer: The Long-Document Transformer](https://arxiv.org/pdf/2004.05150.pdf) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+
+The abstract from the paper is the following:
+
+*Transformer-based models are unable to process long sequences due to their self-attention operation, which scales
+quadratically with the sequence length. To address this limitation, we introduce the Longformer with an attention
+mechanism that scales linearly with sequence length, making it easy to process documents of thousands of tokens or
+longer. Longformer's attention mechanism is a drop-in replacement for the standard self-attention and combines a local
+windowed attention with a task motivated global attention. Following prior work on long-sequence transformers, we
+evaluate Longformer on character-level language modeling and achieve state-of-the-art results on text8 and enwik8. In
+contrast to most prior work, we also pretrain Longformer and finetune it on a variety of downstream tasks. Our
+pretrained Longformer consistently outperforms RoBERTa on long document tasks and sets new state-of-the-art results on
+WikiHop and TriviaQA.*
+
+This model was contributed by [beltagy](https://huggingface.co/beltagy). The Authors' code can be found [here](https://github.com/allenai/longformer).
+
+## Usage tips
+
+- Since the Longformer is based on RoBERTa, it doesn't have `token_type_ids`. You don't need to indicate which
+ token belongs to which segment. Just separate your segments with the separation token `tokenizer.sep_token` (or
+ ``).
+- A transformer model replacing the attention matrices by sparse matrices to go faster. Often, the local context (e.g., what are the two tokens left and right?) is enough to take action for a given token. Some preselected input tokens are still given global attention, but the attention matrix has way less parameters, resulting in a speed-up. See the local attention section for more information.
+
+## Longformer Self Attention
+
+Longformer self attention employs self attention on both a "local" context and a "global" context. Most tokens only
+attend "locally" to each other meaning that each token attends to its \\(\frac{1}{2} w\\) previous tokens and
+\\(\frac{1}{2} w\\) succeeding tokens with \\(w\\) being the window length as defined in
+`config.attention_window`. Note that `config.attention_window` can be of type `List` to define a
+different \\(w\\) for each layer. A selected few tokens attend "globally" to all other tokens, as it is
+conventionally done for all tokens in `BertSelfAttention`.
+
+Note that "locally" and "globally" attending tokens are projected by different query, key and value matrices. Also note
+that every "locally" attending token not only attends to tokens within its window \\(w\\), but also to all "globally"
+attending tokens so that global attention is *symmetric*.
+
+The user can define which tokens attend "locally" and which tokens attend "globally" by setting the tensor
+`global_attention_mask` at run-time appropriately. All Longformer models employ the following logic for
+`global_attention_mask`:
+
+- 0: the token attends "locally",
+- 1: the token attends "globally".
+
+For more information please also refer to [`~LongformerModel.forward`] method.
+
+Using Longformer self attention, the memory and time complexity of the query-key matmul operation, which usually
+represents the memory and time bottleneck, can be reduced from \\(\mathcal{O}(n_s \times n_s)\\) to
+\\(\mathcal{O}(n_s \times w)\\), with \\(n_s\\) being the sequence length and \\(w\\) being the average window
+size. It is assumed that the number of "globally" attending tokens is insignificant as compared to the number of
+"locally" attending tokens.
+
+For more information, please refer to the official [paper](https://arxiv.org/pdf/2004.05150.pdf).
+
+
+## Training
+
+[`LongformerForMaskedLM`] is trained the exact same way [`RobertaForMaskedLM`] is
+trained and should be used as follows:
+
+```python
+input_ids = tokenizer.encode("This is a sentence from [MASK] training data", return_tensors="pt")
+mlm_labels = tokenizer.encode("This is a sentence from the training data", return_tensors="pt")
+
+loss = model(input_ids, labels=input_ids, masked_lm_labels=mlm_labels)[0]
+```
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## LongformerConfig
+
+[[autodoc]] LongformerConfig
+
+## LongformerTokenizer
+
+[[autodoc]] LongformerTokenizer
+
+## LongformerTokenizerFast
+
+[[autodoc]] LongformerTokenizerFast
+
+## Longformer specific outputs
+
+[[autodoc]] models.longformer.modeling_longformer.LongformerBaseModelOutput
+
+[[autodoc]] models.longformer.modeling_longformer.LongformerBaseModelOutputWithPooling
+
+[[autodoc]] models.longformer.modeling_longformer.LongformerMaskedLMOutput
+
+[[autodoc]] models.longformer.modeling_longformer.LongformerQuestionAnsweringModelOutput
+
+[[autodoc]] models.longformer.modeling_longformer.LongformerSequenceClassifierOutput
+
+[[autodoc]] models.longformer.modeling_longformer.LongformerMultipleChoiceModelOutput
+
+[[autodoc]] models.longformer.modeling_longformer.LongformerTokenClassifierOutput
+
+[[autodoc]] models.longformer.modeling_tf_longformer.TFLongformerBaseModelOutput
+
+[[autodoc]] models.longformer.modeling_tf_longformer.TFLongformerBaseModelOutputWithPooling
+
+[[autodoc]] models.longformer.modeling_tf_longformer.TFLongformerMaskedLMOutput
+
+[[autodoc]] models.longformer.modeling_tf_longformer.TFLongformerQuestionAnsweringModelOutput
+
+[[autodoc]] models.longformer.modeling_tf_longformer.TFLongformerSequenceClassifierOutput
+
+[[autodoc]] models.longformer.modeling_tf_longformer.TFLongformerMultipleChoiceModelOutput
+
+[[autodoc]] models.longformer.modeling_tf_longformer.TFLongformerTokenClassifierOutput
+
+
+
+
+## LongformerModel
+
+[[autodoc]] LongformerModel
+ - forward
+
+## LongformerForMaskedLM
+
+[[autodoc]] LongformerForMaskedLM
+ - forward
+
+## LongformerForSequenceClassification
+
+[[autodoc]] LongformerForSequenceClassification
+ - forward
+
+## LongformerForMultipleChoice
+
+[[autodoc]] LongformerForMultipleChoice
+ - forward
+
+## LongformerForTokenClassification
+
+[[autodoc]] LongformerForTokenClassification
+ - forward
+
+## LongformerForQuestionAnswering
+
+[[autodoc]] LongformerForQuestionAnswering
+ - forward
+
+
+
+
+## TFLongformerModel
+
+[[autodoc]] TFLongformerModel
+ - call
+
+## TFLongformerForMaskedLM
+
+[[autodoc]] TFLongformerForMaskedLM
+ - call
+
+## TFLongformerForQuestionAnswering
+
+[[autodoc]] TFLongformerForQuestionAnswering
+ - call
+
+## TFLongformerForSequenceClassification
+
+[[autodoc]] TFLongformerForSequenceClassification
+ - call
+
+## TFLongformerForTokenClassification
+
+[[autodoc]] TFLongformerForTokenClassification
+ - call
+
+## TFLongformerForMultipleChoice
+
+[[autodoc]] TFLongformerForMultipleChoice
+ - call
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/longt5.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/longt5.md
new file mode 100644
index 0000000000000000000000000000000000000000..40faa6d8c2377fb6e68b2bd7ce13eaca803f1314
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/longt5.md
@@ -0,0 +1,139 @@
+
+
+# LongT5
+
+## Overview
+
+The LongT5 model was proposed in [LongT5: Efficient Text-To-Text Transformer for Long Sequences](https://arxiv.org/abs/2112.07916)
+by Mandy Guo, Joshua Ainslie, David Uthus, Santiago Ontanon, Jianmo Ni, Yun-Hsuan Sung and Yinfei Yang. It's an
+encoder-decoder transformer pre-trained in a text-to-text denoising generative setting. LongT5 model is an extension of
+T5 model, and it enables using one of the two different efficient attention mechanisms - (1) Local attention, or (2)
+Transient-Global attention.
+
+
+The abstract from the paper is the following:
+
+*Recent work has shown that either (1) increasing the input length or (2) increasing model size can improve the
+performance of Transformer-based neural models. In this paper, we present a new model, called LongT5, with which we
+explore the effects of scaling both the input length and model size at the same time. Specifically, we integrated
+attention ideas from long-input transformers (ETC), and adopted pre-training strategies from summarization pre-training
+(PEGASUS) into the scalable T5 architecture. The result is a new attention mechanism we call {\em Transient Global}
+(TGlobal), which mimics ETC's local/global attention mechanism, but without requiring additional side-inputs. We are
+able to achieve state-of-the-art results on several summarization tasks and outperform the original T5 models on
+question answering tasks.*
+
+This model was contributed by [stancld](https://huggingface.co/stancld).
+The original code can be found [here](https://github.com/google-research/longt5).
+
+## Usage tips
+
+- [`LongT5ForConditionalGeneration`] is an extension of [`T5ForConditionalGeneration`] exchanging the traditional
+encoder *self-attention* layer with efficient either *local* attention or *transient-global* (*tglobal*) attention.
+- Unlike the T5 model, LongT5 does not use a task prefix. Furthermore, it uses a different pre-training objective
+inspired by the pre-training of [`PegasusForConditionalGeneration`].
+- LongT5 model is designed to work efficiently and very well on long-range *sequence-to-sequence* tasks where the
+input sequence exceeds commonly used 512 tokens. It is capable of handling input sequences of a length up to 16,384 tokens.
+- For *Local Attention*, the sparse sliding-window local attention operation allows a given token to attend only `r`
+tokens to the left and right of it (with `r=127` by default). *Local Attention* does not introduce any new parameters
+to the model. The complexity of the mechanism is linear in input sequence length `l`: `O(l*r)`.
+- *Transient Global Attention* is an extension of the *Local Attention*. It, furthermore, allows each input token to
+interact with all other tokens in the layer. This is achieved via splitting an input sequence into blocks of a fixed
+length `k` (with a default `k=16`). Then, a global token for such a block is obtained via summing and normalizing the embeddings of every token
+in the block. Thanks to this, the attention allows each token to attend to both nearby tokens like in Local attention, and
+also every global token like in the case of standard global attention (*transient* represents the fact the global tokens
+are constructed dynamically within each attention operation). As a consequence, *TGlobal* attention introduces
+a few new parameters -- global relative position biases and a layer normalization for global token's embedding.
+The complexity of this mechanism is `O(l(r + l/k))`.
+- An example showing how to evaluate a fine-tuned LongT5 model on the [pubmed dataset](https://huggingface.co/datasets/scientific_papers) is below.
+
+```python
+>>> import evaluate
+>>> from datasets import load_dataset
+>>> from transformers import AutoTokenizer, LongT5ForConditionalGeneration
+
+>>> dataset = load_dataset("scientific_papers", "pubmed", split="validation")
+>>> model = (
+... LongT5ForConditionalGeneration.from_pretrained("Stancld/longt5-tglobal-large-16384-pubmed-3k_steps")
+... .to("cuda")
+... .half()
+... )
+>>> tokenizer = AutoTokenizer.from_pretrained("Stancld/longt5-tglobal-large-16384-pubmed-3k_steps")
+
+
+>>> def generate_answers(batch):
+... inputs_dict = tokenizer(
+... batch["article"], max_length=16384, padding="max_length", truncation=True, return_tensors="pt"
+... )
+... input_ids = inputs_dict.input_ids.to("cuda")
+... attention_mask = inputs_dict.attention_mask.to("cuda")
+... output_ids = model.generate(input_ids, attention_mask=attention_mask, max_length=512, num_beams=2)
+... batch["predicted_abstract"] = tokenizer.batch_decode(output_ids, skip_special_tokens=True)
+... return batch
+
+
+>>> result = dataset.map(generate_answer, batched=True, batch_size=2)
+>>> rouge = evaluate.load("rouge")
+>>> rouge.compute(predictions=result["predicted_abstract"], references=result["abstract"])
+```
+
+
+## Resources
+
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## LongT5Config
+
+[[autodoc]] LongT5Config
+
+
+
+
+## LongT5Model
+
+[[autodoc]] LongT5Model
+ - forward
+
+## LongT5ForConditionalGeneration
+
+[[autodoc]] LongT5ForConditionalGeneration
+ - forward
+
+## LongT5EncoderModel
+
+[[autodoc]] LongT5EncoderModel
+ - forward
+
+
+
+
+## FlaxLongT5Model
+
+[[autodoc]] FlaxLongT5Model
+ - __call__
+ - encode
+ - decode
+
+## FlaxLongT5ForConditionalGeneration
+
+[[autodoc]] FlaxLongT5ForConditionalGeneration
+ - __call__
+ - encode
+ - decode
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/luke.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/luke.md
new file mode 100644
index 0000000000000000000000000000000000000000..4e070b1c4bac3ee3c4e0c936a85f8a235bf7b8ad
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/luke.md
@@ -0,0 +1,181 @@
+
+
+# LUKE
+
+## Overview
+
+The LUKE model was proposed in [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://arxiv.org/abs/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda and Yuji Matsumoto.
+It is based on RoBERTa and adds entity embeddings as well as an entity-aware self-attention mechanism, which helps
+improve performance on various downstream tasks involving reasoning about entities such as named entity recognition,
+extractive and cloze-style question answering, entity typing, and relation classification.
+
+The abstract from the paper is the following:
+
+*Entity representations are useful in natural language tasks involving entities. In this paper, we propose new
+pretrained contextualized representations of words and entities based on the bidirectional transformer. The proposed
+model treats words and entities in a given text as independent tokens, and outputs contextualized representations of
+them. Our model is trained using a new pretraining task based on the masked language model of BERT. The task involves
+predicting randomly masked words and entities in a large entity-annotated corpus retrieved from Wikipedia. We also
+propose an entity-aware self-attention mechanism that is an extension of the self-attention mechanism of the
+transformer, and considers the types of tokens (words or entities) when computing attention scores. The proposed model
+achieves impressive empirical performance on a wide range of entity-related tasks. In particular, it obtains
+state-of-the-art results on five well-known datasets: Open Entity (entity typing), TACRED (relation classification),
+CoNLL-2003 (named entity recognition), ReCoRD (cloze-style question answering), and SQuAD 1.1 (extractive question
+answering).*
+
+This model was contributed by [ikuyamada](https://huggingface.co/ikuyamada) and [nielsr](https://huggingface.co/nielsr). The original code can be found [here](https://github.com/studio-ousia/luke).
+
+## Usage tips
+
+- This implementation is the same as [`RobertaModel`] with the addition of entity embeddings as well
+ as an entity-aware self-attention mechanism, which improves performance on tasks involving reasoning about entities.
+- LUKE treats entities as input tokens; therefore, it takes `entity_ids`, `entity_attention_mask`,
+ `entity_token_type_ids` and `entity_position_ids` as extra input. You can obtain those using
+ [`LukeTokenizer`].
+- [`LukeTokenizer`] takes `entities` and `entity_spans` (character-based start and end
+ positions of the entities in the input text) as extra input. `entities` typically consist of [MASK] entities or
+ Wikipedia entities. The brief description when inputting these entities are as follows:
+
+ - *Inputting [MASK] entities to compute entity representations*: The [MASK] entity is used to mask entities to be
+ predicted during pretraining. When LUKE receives the [MASK] entity, it tries to predict the original entity by
+ gathering the information about the entity from the input text. Therefore, the [MASK] entity can be used to address
+ downstream tasks requiring the information of entities in text such as entity typing, relation classification, and
+ named entity recognition.
+ - *Inputting Wikipedia entities to compute knowledge-enhanced token representations*: LUKE learns rich information
+ (or knowledge) about Wikipedia entities during pretraining and stores the information in its entity embedding. By
+ using Wikipedia entities as input tokens, LUKE outputs token representations enriched by the information stored in
+ the embeddings of these entities. This is particularly effective for tasks requiring real-world knowledge, such as
+ question answering.
+
+- There are three head models for the former use case:
+
+ - [`LukeForEntityClassification`], for tasks to classify a single entity in an input text such as
+ entity typing, e.g. the [Open Entity dataset](https://www.cs.utexas.edu/~eunsol/html_pages/open_entity.html).
+ This model places a linear head on top of the output entity representation.
+ - [`LukeForEntityPairClassification`], for tasks to classify the relationship between two entities
+ such as relation classification, e.g. the [TACRED dataset](https://nlp.stanford.edu/projects/tacred/). This
+ model places a linear head on top of the concatenated output representation of the pair of given entities.
+ - [`LukeForEntitySpanClassification`], for tasks to classify the sequence of entity spans, such as
+ named entity recognition (NER). This model places a linear head on top of the output entity representations. You
+ can address NER using this model by inputting all possible entity spans in the text to the model.
+
+ [`LukeTokenizer`] has a `task` argument, which enables you to easily create an input to these
+ head models by specifying `task="entity_classification"`, `task="entity_pair_classification"`, or
+ `task="entity_span_classification"`. Please refer to the example code of each head models.
+
+Usage example:
+
+```python
+>>> from transformers import LukeTokenizer, LukeModel, LukeForEntityPairClassification
+
+>>> model = LukeModel.from_pretrained("studio-ousia/luke-base")
+>>> tokenizer = LukeTokenizer.from_pretrained("studio-ousia/luke-base")
+# Example 1: Computing the contextualized entity representation corresponding to the entity mention "Beyoncé"
+
+>>> text = "Beyoncé lives in Los Angeles."
+>>> entity_spans = [(0, 7)] # character-based entity span corresponding to "Beyoncé"
+>>> inputs = tokenizer(text, entity_spans=entity_spans, add_prefix_space=True, return_tensors="pt")
+>>> outputs = model(**inputs)
+>>> word_last_hidden_state = outputs.last_hidden_state
+>>> entity_last_hidden_state = outputs.entity_last_hidden_state
+# Example 2: Inputting Wikipedia entities to obtain enriched contextualized representations
+
+>>> entities = [
+... "Beyoncé",
+... "Los Angeles",
+... ] # Wikipedia entity titles corresponding to the entity mentions "Beyoncé" and "Los Angeles"
+>>> entity_spans = [(0, 7), (17, 28)] # character-based entity spans corresponding to "Beyoncé" and "Los Angeles"
+>>> inputs = tokenizer(text, entities=entities, entity_spans=entity_spans, add_prefix_space=True, return_tensors="pt")
+>>> outputs = model(**inputs)
+>>> word_last_hidden_state = outputs.last_hidden_state
+>>> entity_last_hidden_state = outputs.entity_last_hidden_state
+# Example 3: Classifying the relationship between two entities using LukeForEntityPairClassification head model
+
+>>> model = LukeForEntityPairClassification.from_pretrained("studio-ousia/luke-large-finetuned-tacred")
+>>> tokenizer = LukeTokenizer.from_pretrained("studio-ousia/luke-large-finetuned-tacred")
+>>> entity_spans = [(0, 7), (17, 28)] # character-based entity spans corresponding to "Beyoncé" and "Los Angeles"
+>>> inputs = tokenizer(text, entity_spans=entity_spans, return_tensors="pt")
+>>> outputs = model(**inputs)
+>>> logits = outputs.logits
+>>> predicted_class_idx = int(logits[0].argmax())
+>>> print("Predicted class:", model.config.id2label[predicted_class_idx])
+```
+
+## Resources
+
+- [A demo notebook on how to fine-tune [`LukeForEntityPairClassification`] for relation classification](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/LUKE)
+- [Notebooks showcasing how you to reproduce the results as reported in the paper with the HuggingFace implementation of LUKE](https://github.com/studio-ousia/luke/tree/master/notebooks)
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## LukeConfig
+
+[[autodoc]] LukeConfig
+
+## LukeTokenizer
+
+[[autodoc]] LukeTokenizer
+ - __call__
+ - save_vocabulary
+
+## LukeModel
+
+[[autodoc]] LukeModel
+ - forward
+
+## LukeForMaskedLM
+
+[[autodoc]] LukeForMaskedLM
+ - forward
+
+## LukeForEntityClassification
+
+[[autodoc]] LukeForEntityClassification
+ - forward
+
+## LukeForEntityPairClassification
+
+[[autodoc]] LukeForEntityPairClassification
+ - forward
+
+## LukeForEntitySpanClassification
+
+[[autodoc]] LukeForEntitySpanClassification
+ - forward
+
+## LukeForSequenceClassification
+
+[[autodoc]] LukeForSequenceClassification
+ - forward
+
+## LukeForMultipleChoice
+
+[[autodoc]] LukeForMultipleChoice
+ - forward
+
+## LukeForTokenClassification
+
+[[autodoc]] LukeForTokenClassification
+ - forward
+
+## LukeForQuestionAnswering
+
+[[autodoc]] LukeForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/lxmert.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/lxmert.md
new file mode 100644
index 0000000000000000000000000000000000000000..435994196b43ba7cf3604d3ba4bec0dfccba5222
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/lxmert.md
@@ -0,0 +1,118 @@
+
+
+# LXMERT
+
+## Overview
+
+The LXMERT model was proposed in [LXMERT: Learning Cross-Modality Encoder Representations from Transformers](https://arxiv.org/abs/1908.07490) by Hao Tan & Mohit Bansal. It is a series of bidirectional transformer encoders
+(one for the vision modality, one for the language modality, and then one to fuse both modalities) pretrained using a
+combination of masked language modeling, visual-language text alignment, ROI-feature regression, masked
+visual-attribute modeling, masked visual-object modeling, and visual-question answering objectives. The pretraining
+consists of multiple multi-modal datasets: MSCOCO, Visual-Genome + Visual-Genome Question Answering, VQA 2.0, and GQA.
+
+The abstract from the paper is the following:
+
+*Vision-and-language reasoning requires an understanding of visual concepts, language semantics, and, most importantly,
+the alignment and relationships between these two modalities. We thus propose the LXMERT (Learning Cross-Modality
+Encoder Representations from Transformers) framework to learn these vision-and-language connections. In LXMERT, we
+build a large-scale Transformer model that consists of three encoders: an object relationship encoder, a language
+encoder, and a cross-modality encoder. Next, to endow our model with the capability of connecting vision and language
+semantics, we pre-train the model with large amounts of image-and-sentence pairs, via five diverse representative
+pretraining tasks: masked language modeling, masked object prediction (feature regression and label classification),
+cross-modality matching, and image question answering. These tasks help in learning both intra-modality and
+cross-modality relationships. After fine-tuning from our pretrained parameters, our model achieves the state-of-the-art
+results on two visual question answering datasets (i.e., VQA and GQA). We also show the generalizability of our
+pretrained cross-modality model by adapting it to a challenging visual-reasoning task, NLVR, and improve the previous
+best result by 22% absolute (54% to 76%). Lastly, we demonstrate detailed ablation studies to prove that both our novel
+model components and pretraining strategies significantly contribute to our strong results; and also present several
+attention visualizations for the different encoders*
+
+This model was contributed by [eltoto1219](https://huggingface.co/eltoto1219). The original code can be found [here](https://github.com/airsplay/lxmert).
+
+## Usage tips
+
+- Bounding boxes are not necessary to be used in the visual feature embeddings, any kind of visual-spacial features
+ will work.
+- Both the language hidden states and the visual hidden states that LXMERT outputs are passed through the
+ cross-modality layer, so they contain information from both modalities. To access a modality that only attends to
+ itself, select the vision/language hidden states from the first input in the tuple.
+- The bidirectional cross-modality encoder attention only returns attention values when the language modality is used
+ as the input and the vision modality is used as the context vector. Further, while the cross-modality encoder
+ contains self-attention for each respective modality and cross-attention, only the cross attention is returned and
+ both self attention outputs are disregarded.
+
+## Resources
+
+- [Question answering task guide](../tasks/question_answering)
+
+## LxmertConfig
+
+[[autodoc]] LxmertConfig
+
+## LxmertTokenizer
+
+[[autodoc]] LxmertTokenizer
+
+## LxmertTokenizerFast
+
+[[autodoc]] LxmertTokenizerFast
+
+## Lxmert specific outputs
+
+[[autodoc]] models.lxmert.modeling_lxmert.LxmertModelOutput
+
+[[autodoc]] models.lxmert.modeling_lxmert.LxmertForPreTrainingOutput
+
+[[autodoc]] models.lxmert.modeling_lxmert.LxmertForQuestionAnsweringOutput
+
+[[autodoc]] models.lxmert.modeling_tf_lxmert.TFLxmertModelOutput
+
+[[autodoc]] models.lxmert.modeling_tf_lxmert.TFLxmertForPreTrainingOutput
+
+
+
+
+## LxmertModel
+
+[[autodoc]] LxmertModel
+ - forward
+
+## LxmertForPreTraining
+
+[[autodoc]] LxmertForPreTraining
+ - forward
+
+## LxmertForQuestionAnswering
+
+[[autodoc]] LxmertForQuestionAnswering
+ - forward
+
+
+
+
+## TFLxmertModel
+
+[[autodoc]] TFLxmertModel
+ - call
+
+## TFLxmertForPreTraining
+
+[[autodoc]] TFLxmertForPreTraining
+ - call
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/m2m_100.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/m2m_100.md
new file mode 100644
index 0000000000000000000000000000000000000000..d64545fafb06120e1e6ee5e6155b02b51b9cc4ee
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/m2m_100.md
@@ -0,0 +1,183 @@
+
+
+# M2M100
+
+## Overview
+
+The M2M100 model was proposed in [Beyond English-Centric Multilingual Machine Translation](https://arxiv.org/abs/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky,
+Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy
+Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
+
+The abstract from the paper is the following:
+
+*Existing work in translation demonstrated the potential of massively multilingual machine translation by training a
+single model able to translate between any pair of languages. However, much of this work is English-Centric by training
+only on data which was translated from or to English. While this is supported by large sources of training data, it
+does not reflect translation needs worldwide. In this work, we create a true Many-to-Many multilingual translation
+model that can translate directly between any pair of 100 languages. We build and open source a training dataset that
+covers thousands of language directions with supervised data, created through large-scale mining. Then, we explore how
+to effectively increase model capacity through a combination of dense scaling and language-specific sparse parameters
+to create high quality models. Our focus on non-English-Centric models brings gains of more than 10 BLEU when directly
+translating between non-English directions while performing competitively to the best single systems of WMT. We
+open-source our scripts so that others may reproduce the data, evaluation, and final M2M-100 model.*
+
+This model was contributed by [valhalla](https://huggingface.co/valhalla).
+
+
+## Usage tips and examples
+
+M2M100 is a multilingual encoder-decoder (seq-to-seq) model primarily intended for translation tasks. As the model is
+multilingual it expects the sequences in a certain format: A special language id token is used as prefix in both the
+source and target text. The source text format is `[lang_code] X [eos]`, where `lang_code` is source language
+id for source text and target language id for target text, with `X` being the source or target text.
+
+The [`M2M100Tokenizer`] depends on `sentencepiece` so be sure to install it before running the
+examples. To install `sentencepiece` run `pip install sentencepiece`.
+
+**Supervised Training**
+
+```python
+from transformers import M2M100Config, M2M100ForConditionalGeneration, M2M100Tokenizer
+
+model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M")
+tokenizer = M2M100Tokenizer.from_pretrained("facebook/m2m100_418M", src_lang="en", tgt_lang="fr")
+
+src_text = "Life is like a box of chocolates."
+tgt_text = "La vie est comme une boîte de chocolat."
+
+model_inputs = tokenizer(src_text, text_target=tgt_text, return_tensors="pt")
+
+loss = model(**model_inputs).loss # forward pass
+```
+
+**Generation**
+
+M2M100 uses the `eos_token_id` as the `decoder_start_token_id` for generation with the target language id
+being forced as the first generated token. To force the target language id as the first generated token, pass the
+*forced_bos_token_id* parameter to the *generate* method. The following example shows how to translate between
+Hindi to French and Chinese to English using the *facebook/m2m100_418M* checkpoint.
+
+```python
+>>> from transformers import M2M100ForConditionalGeneration, M2M100Tokenizer
+
+>>> hi_text = "जीवन एक चॉकलेट बॉक्स की तरह है।"
+>>> chinese_text = "生活就像一盒巧克力。"
+
+>>> model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M")
+>>> tokenizer = M2M100Tokenizer.from_pretrained("facebook/m2m100_418M")
+
+>>> # translate Hindi to French
+>>> tokenizer.src_lang = "hi"
+>>> encoded_hi = tokenizer(hi_text, return_tensors="pt")
+>>> generated_tokens = model.generate(**encoded_hi, forced_bos_token_id=tokenizer.get_lang_id("fr"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+"La vie est comme une boîte de chocolat."
+
+>>> # translate Chinese to English
+>>> tokenizer.src_lang = "zh"
+>>> encoded_zh = tokenizer(chinese_text, return_tensors="pt")
+>>> generated_tokens = model.generate(**encoded_zh, forced_bos_token_id=tokenizer.get_lang_id("en"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+"Life is like a box of chocolate."
+```
+
+## Resources
+
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## M2M100Config
+
+[[autodoc]] M2M100Config
+
+## M2M100Tokenizer
+
+[[autodoc]] M2M100Tokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## M2M100Model
+
+[[autodoc]] M2M100Model
+ - forward
+
+## M2M100ForConditionalGeneration
+
+[[autodoc]] M2M100ForConditionalGeneration
+ - forward
+
+## Using Flash Attention 2
+
+Flash Attention 2 is a faster, optimized version of the attention scores computation which relies on `cuda` kernels.
+
+### Installation
+
+First, check whether your hardware is compatible with Flash Attention 2. The latest list of compatible hardware can be found in the [official documentation](https://github.com/Dao-AILab/flash-attention#installation-and-features).
+
+Next, [install](https://github.com/Dao-AILab/flash-attention#installation-and-features) the latest version of Flash Attention 2:
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+### Usage
+
+To load a model using Flash Attention 2, we can pass the argument `attn_implementation="flash_attention_2"` to [`.from_pretrained`](https://huggingface.co/docs/transformers/main/en/main_classes/model#transformers.PreTrainedModel.from_pretrained). You can use either `torch.float16` or `torch.bfloat16` precision.
+
+```python
+>>> import torch
+>>> from transformers import M2M100ForConditionalGeneration, M2M100Tokenizer
+
+>>> model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M", torch_dtype=torch.float16, attn_implementation="flash_attention_2").to("cuda").eval()
+>>> tokenizer = M2M100Tokenizer.from_pretrained("facebook/m2m100_418M")
+
+>>> # translate Hindi to French
+>>> hi_text = "जीवन एक चॉकलेट बॉक्स की तरह है।"
+>>> tokenizer.src_lang = "hi"
+>>> encoded_hi = tokenizer(hi_text, return_tensors="pt").to("cuda")
+>>> generated_tokens = model.generate(**encoded_hi, forced_bos_token_id=tokenizer.get_lang_id("fr"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+"La vie est comme une boîte de chocolat."
+```
+
+### Expected speedups
+
+Below is an expected speedup diagram that compares pure inference time between the native implementation and the Flash Attention 2.
+
+
+
+
+
+## Using Scaled Dot Product Attention (SDPA)
+PyTorch includes a native scaled dot-product attention (SDPA) operator as part of `torch.nn.functional`. This function
+encompasses several implementations that can be applied depending on the inputs and the hardware in use. See the
+[official documentation](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)
+or the [GPU Inference](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)
+page for more information.
+
+SDPA is used by default for `torch>=2.1.1` when an implementation is available, but you may also set
+`attn_implementation="sdpa"` in `from_pretrained()` to explicitly request SDPA to be used.
+
+```python
+from transformers import M2M100ForConditionalGeneration
+model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M", torch_dtype=torch.float16, attn_implementation="sdpa")
+...
+```
+
+For the best speedups, we recommend loading the model in half-precision (e.g. `torch.float16` or `torch.bfloat16`).
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/madlad-400.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/madlad-400.md
new file mode 100644
index 0000000000000000000000000000000000000000..aeb41938499c2971d7a1a90bfd893e410ff49222
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/madlad-400.md
@@ -0,0 +1,68 @@
+
+
+# MADLAD-400
+
+## Overview
+
+MADLAD-400 models were released in the paper [MADLAD-400: A Multilingual And Document-Level Large Audited Dataset](MADLAD-400: A Multilingual And Document-Level Large Audited Dataset).
+
+The abstract from the paper is the following:
+
+*We introduce MADLAD-400, a manually audited, general domain 3T token monolingual dataset based on CommonCrawl, spanning 419 languages. We discuss
+the limitations revealed by self-auditing MADLAD-400, and the role data auditing
+had in the dataset creation process. We then train and release a 10.7B-parameter
+multilingual machine translation model on 250 billion tokens covering over 450
+languages using publicly available data, and find that it is competitive with models
+that are significantly larger, and report the results on different domains. In addition, we train a 8B-parameter language model, and assess the results on few-shot
+translation. We make the baseline models 1
+available to the research community.*
+
+This model was added by [Juarez Bochi](https://huggingface.co/jbochi). The original checkpoints can be found [here](https://github.com/google-research/google-research/tree/master/madlad_400).
+
+This is a machine translation model that supports many low-resource languages, and that is competitive with models that are significantly larger.
+
+One can directly use MADLAD-400 weights without finetuning the model:
+
+```python
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("google/madlad400-3b-mt")
+>>> tokenizer = AutoTokenizer.from_pretrained("google/madlad400-3b-mt")
+
+>>> inputs = tokenizer("<2pt> I love pizza!", return_tensors="pt")
+>>> outputs = model.generate(**inputs)
+>>> print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['Eu amo pizza!']
+```
+
+Google has released the following variants:
+
+- [google/madlad400-3b-mt](https://huggingface.co/google/madlad400-3b-mt)
+
+- [google/madlad400-7b-mt](https://huggingface.co/google/madlad400-7b-mt)
+
+- [google/madlad400-7b-mt-bt](https://huggingface.co/google/madlad400-7b-mt-bt)
+
+- [google/madlad400-10b-mt](https://huggingface.co/google/madlad400-10b-mt)
+
+The original checkpoints can be found [here](https://github.com/google-research/google-research/tree/master/madlad_400).
+
+
+
+Refer to [T5's documentation page](t5) for all API references, code examples, and notebooks. For more details regarding training and evaluation of the MADLAD-400, refer to the model card.
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mamba.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mamba.md
new file mode 100644
index 0000000000000000000000000000000000000000..317948331eb10294a03bb505f7f7597a2e25e8a6
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mamba.md
@@ -0,0 +1,104 @@
+
+
+# Mamba
+
+## Overview
+
+The Mamba model was proposed in [Mamba: Linear-Time Sequence Modeling with Selective State Spaces](https://arxiv.org/abs/2312.00752) by Albert Gu and Tri Dao.
+
+This model is a new paradigm architecture based on `state-space-models`. You can read more about the intuition behind these [here](https://srush.github.io/annotated-s4/).
+
+The abstract from the paper is the following:
+
+*Foundation models, now powering most of the exciting applications in deep learning, are almost universally based on the Transformer architecture and its core attention module. Many subquadratic-time architectures such as linear attention, gated convolution and recurrent models, and structured state space models (SSMs) have been developed to address Transformers' computational inefficiency on long sequences, but they have not performed as well as attention on important modalities such as language. We identify that a key weakness of such models is their inability to perform content-based reasoning, and make several improvements. First, simply letting the SSM parameters be functions of the input addresses their weakness with discrete modalities, allowing the model to selectively propagate or forget information along the sequence length dimension depending on the current token. Second, even though this change prevents the use of efficient convolutions, we design a hardware-aware parallel algorithm in recurrent mode. We integrate these selective SSMs into a simplified end-to-end neural network architecture without attention or even MLP blocks (Mamba). Mamba enjoys fast inference (5× higher throughput than Transformers) and linear scaling in sequence length, and its performance improves on real data up to million-length sequences. As a general sequence model backbone, Mamba achieves state-of-the-art performance across several modalities such as language, audio, and genomics. On language modeling, our Mamba-3B model outperforms Transformers of the same size and matches Transformers twice its size, both in pretraining and downstream evaluation.*
+
+Tips:
+
+- Mamba is a new `state space model` architecture that rivals the classic Transformers. It is based on the line of progress on structured state space models, with an efficient hardware-aware design and implementation in the spirit of [FlashAttention](https://github.com/Dao-AILab/flash-attention).
+- Mamba stacks `mixer` layers, which are the equivalent of `Attention` layers. The core logic of `mamba` is held in the `MambaMixer` class.
+- Two implementations cohabit: one is optimized and uses fast cuda kernels, while the other one is naive but can run on any device!
+- The current implementation leverages the original cuda kernels: the equivalent of flash attention for Mamba are hosted in the [`mamba-ssm`](https://github.com/state-spaces/mamba) and the [`causal_conv1d`](https://github.com/Dao-AILab/causal-conv1d) repositories. Make sure to install them if your hardware supports them!
+- Contributions to make the naive path faster are welcome 🤗
+
+This model was contributed by [ArthurZ](https://huggingface.co/ArthurZ).
+The original code can be found [here](https://github.com/state-spaces/mamba).
+
+# Usage
+
+### A simple generation example:
+```python
+from transformers import MambaConfig, MambaForCausalLM, AutoTokenizer
+import torch
+
+tokenizer = AutoTokenizer.from_pretrained("state-spaces/mamba-130m-hf")
+model = MambaForCausalLM.from_pretrained("state-spaces/mamba-130m-hf")
+input_ids = tokenizer("Hey how are you doing?", return_tensors= "pt")["input_ids"]
+
+out = model.generate(input_ids, max_new_tokens=10)
+print(tokenizer.batch_decode(out))
+```
+
+### Peft finetuning
+The slow version is not very stable for training, and the fast one needs `float32`!
+
+```python
+from datasets import load_dataset
+from trl import SFTTrainer
+from peft import LoraConfig
+from transformers import AutoTokenizer, AutoModelForCausalLM, TrainingArguments
+model_id = "state-spaces/mamba-130m-hf"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id)
+dataset = load_dataset("Abirate/english_quotes", split="train")
+training_args = TrainingArguments(
+ output_dir="./results",
+ num_train_epochs=3,
+ per_device_train_batch_size=4,
+ logging_dir='./logs',
+ logging_steps=10,
+ learning_rate=2e-3
+)
+lora_config = LoraConfig(
+ r=8,
+ target_modules=["x_proj", "embeddings", "in_proj", "out_proj"],
+ task_type="CAUSAL_LM",
+ bias="none"
+)
+trainer = SFTTrainer(
+ model=model,
+ processing_class=tokenizer,
+ args=training_args,
+ peft_config=lora_config,
+ train_dataset=dataset,
+ dataset_text_field="quote",
+)
+trainer.train()
+```
+
+## MambaConfig
+
+[[autodoc]] MambaConfig
+
+## MambaModel
+
+[[autodoc]] MambaModel
+ - forward
+
+## MambaLMHeadModel
+
+[[autodoc]] MambaForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mamba2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mamba2.md
new file mode 100644
index 0000000000000000000000000000000000000000..5ed27881cf18ae6eb752bbe0c6a31e455c3c462d
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mamba2.md
@@ -0,0 +1,106 @@
+
+
+# Mamba 2
+
+## Overview
+
+The Mamba2 model was proposed in [Transformers are SSMs: Generalized Models and Efficient Algorithms Through Structured State Space Duality](https://arxiv.org/abs/2405.21060) by Tri Dao and Albert Gu. It is a State Space Model similar to Mamba 1, with better performances in a simplified architecture.
+
+
+The abstract from the paper is the following:
+
+*While Transformers have been the main architecture behind deep learning's success in language modeling, state-space models (SSMs) such as Mamba have recently been shown to match or outperform Transformers at small to medium scale. We show that these families of models are actually quite closely related, and develop a rich framework of theoretical connections between SSMs and variants of attention, connected through various decompositions of a well-studied class of structured semiseparable matrices. Our state space duality (SSD) framework allows us to design a new architecture (Mamba-2) whose core layer is an a refinement of Mamba's selective SSM that is 2-8X faster, while continuing to be competitive with Transformers on language modeling.*
+
+Tips:
+
+This version should support all implementations of Mamba 2, and in particular [Mamba-2 codestral](https://huggingface.co/mistralai/Mamba-Codestral-7B-v0.1) from Mistral AI. In particular, mamba 2 codestral was released with a number of `groups` equal to 8, which can be thought intuitively as similar to the number of kv heads in an attention-based model.
+This model has two different forward passes, `torch_forward` or `cuda_kernels_forward`. The latter uses the original cuda kernels if they are found in your environment, and is slower on the prefill i.e. requires a "warmup run" due to high cpu overhead, see [here](https://github.com/state-spaces/mamba/issues/389#issuecomment-2171755306) and [also here](https://github.com/state-spaces/mamba/issues/355#issuecomment-2147597457). Without compilation, the `torch_forward` implementation is faster by a factor 3 to 4. Further, there are no positional embeddings in this model, but there is an `attention_mask` and a specific logic to mask out hidden states in two places in the case of batched generation, see [here](https://github.com/state-spaces/mamba/issues/66#issuecomment-1863563829) as well. Due to this, in addition to the reimplementation of mamba2 kernels, batched generation and cached generation are expected to have slight discrepancies. Further, the results given by the cuda kernels or the torch forward are expected to be slightly different. The SSM algorithm heavily relies on tensor contractions, which have matmul equivalents but the order of operations is slightly different, making the difference greater at smaller precisions.
+Another note, shutdown of hidden states corresponding to padding tokens is done in 2 places and mostly has been tested with left-padding. Right-padding will propagate noise down the line and is not guaranteed to yield satisfactory results. `tokenizer.padding_side = "left"` ensures you are using the correct padding side.
+
+This model was contributed by [Molbap](https://huggingface.co/Molbap), with tremendous help from [Anton Vlasjuk](https://github.com/vasqu).
+The original code can be found [here](https://github.com/state-spaces/mamba).
+
+
+# Usage
+
+### A simple generation example:
+```python
+from transformers import Mamba2Config, Mamba2ForCausalLM, AutoTokenizer
+import torch
+model_id = 'mistralai/Mamba-Codestral-7B-v0.1'
+tokenizer = AutoTokenizer.from_pretrained(model_id, revision='refs/pr/9', from_slow=True, legacy=False)
+model = Mamba2ForCausalLM.from_pretrained(model_id, revision='refs/pr/9')
+input_ids = tokenizer("Hey how are you doing?", return_tensors= "pt")["input_ids"]
+
+out = model.generate(input_ids, max_new_tokens=10)
+print(tokenizer.batch_decode(out))
+```
+
+Here's a draft script for finetuning:
+```python
+from trl import SFTTrainer
+from peft import LoraConfig
+from transformers import AutoTokenizer, Mamba2ForCausalLM, TrainingArguments
+model_id = 'mistralai/Mamba-Codestral-7B-v0.1'
+tokenizer = AutoTokenizer.from_pretrained(model_id, revision='refs/pr/9', from_slow=True, legacy=False)
+tokenizer.pad_token = tokenizer.eos_token
+tokenizer.padding_side = "left" #enforce padding side left
+
+model = Mamba2ForCausalLM.from_pretrained(model_id, revision='refs/pr/9')
+dataset = load_dataset("Abirate/english_quotes", split="train")
+# Without CUDA kernels, batch size of 2 occupies one 80GB device
+# but precision can be reduced.
+# Experiments and trials welcome!
+training_args = TrainingArguments(
+ output_dir="./results",
+ num_train_epochs=3,
+ per_device_train_batch_size=2,
+ logging_dir='./logs',
+ logging_steps=10,
+ learning_rate=2e-3
+)
+lora_config = LoraConfig(
+ r=8,
+ target_modules=["embeddings", "in_proj", "out_proj"],
+ task_type="CAUSAL_LM",
+ bias="none"
+)
+trainer = SFTTrainer(
+ model=model,
+ tokenizer=tokenizer,
+ args=training_args,
+ peft_config=lora_config,
+ train_dataset=dataset,
+ dataset_text_field="quote",
+)
+trainer.train()
+```
+
+
+## Mamba2Config
+
+[[autodoc]] Mamba2Config
+
+## Mamba2Model
+
+[[autodoc]] Mamba2Model
+ - forward
+
+## Mamba2LMHeadModel
+
+[[autodoc]] Mamba2ForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/marian.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/marian.md
new file mode 100644
index 0000000000000000000000000000000000000000..d8ebec8ffb0ad2e42ad53dd9b6ce1b237e81d65c
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/marian.md
@@ -0,0 +1,225 @@
+
+
+# MarianMT
+
+
+
+## Overview
+
+A framework for translation models, using the same models as BART. Translations should be similar, but not identical to output in the test set linked to in each model card.
+This model was contributed by [sshleifer](https://huggingface.co/sshleifer).
+
+
+## Implementation Notes
+
+- Each model is about 298 MB on disk, there are more than 1,000 models.
+- The list of supported language pairs can be found [here](https://huggingface.co/Helsinki-NLP).
+- Models were originally trained by [Jörg Tiedemann](https://researchportal.helsinki.fi/en/persons/j%C3%B6rg-tiedemann) using the [Marian](https://marian-nmt.github.io/) C++ library, which supports fast training and translation.
+- All models are transformer encoder-decoders with 6 layers in each component. Each model's performance is documented
+ in a model card.
+- The 80 opus models that require BPE preprocessing are not supported.
+- The modeling code is the same as [`BartForConditionalGeneration`] with a few minor modifications:
+
+ - static (sinusoid) positional embeddings (`MarianConfig.static_position_embeddings=True`)
+ - no layernorm_embedding (`MarianConfig.normalize_embedding=False`)
+ - the model starts generating with `pad_token_id` (which has 0 as a token_embedding) as the prefix (Bart uses
+ ``),
+- Code to bulk convert models can be found in `convert_marian_to_pytorch.py`.
+
+
+## Naming
+
+- All model names use the following format: `Helsinki-NLP/opus-mt-{src}-{tgt}`
+- The language codes used to name models are inconsistent. Two digit codes can usually be found [here](https://developers.google.com/admin-sdk/directory/v1/languages), three digit codes require googling "language
+ code {code}".
+- Codes formatted like `es_AR` are usually `code_{region}`. That one is Spanish from Argentina.
+- The models were converted in two stages. The first 1000 models use ISO-639-2 codes to identify languages, the second
+ group use a combination of ISO-639-5 codes and ISO-639-2 codes.
+
+
+## Examples
+
+- Since Marian models are smaller than many other translation models available in the library, they can be useful for
+ fine-tuning experiments and integration tests.
+- [Fine-tune on GPU](https://github.com/huggingface/transformers/blob/master/examples/legacy/seq2seq/train_distil_marian_enro.sh)
+
+## Multilingual Models
+
+- All model names use the following format: `Helsinki-NLP/opus-mt-{src}-{tgt}`:
+- If a model can output multiple languages, and you should specify a language code by prepending the desired output
+ language to the `src_text`.
+- You can see a models's supported language codes in its model card, under target constituents, like in [opus-mt-en-roa](https://huggingface.co/Helsinki-NLP/opus-mt-en-roa).
+- Note that if a model is only multilingual on the source side, like `Helsinki-NLP/opus-mt-roa-en`, no language
+ codes are required.
+
+New multi-lingual models from the [Tatoeba-Challenge repo](https://github.com/Helsinki-NLP/Tatoeba-Challenge)
+require 3 character language codes:
+
+```python
+>>> from transformers import MarianMTModel, MarianTokenizer
+
+>>> src_text = [
+... ">>fra<< this is a sentence in english that we want to translate to french",
+... ">>por<< This should go to portuguese",
+... ">>esp<< And this to Spanish",
+... ]
+
+>>> model_name = "Helsinki-NLP/opus-mt-en-roa"
+>>> tokenizer = MarianTokenizer.from_pretrained(model_name)
+>>> print(tokenizer.supported_language_codes)
+['>>zlm_Latn<<', '>>mfe<<', '>>hat<<', '>>pap<<', '>>ast<<', '>>cat<<', '>>ind<<', '>>glg<<', '>>wln<<', '>>spa<<', '>>fra<<', '>>ron<<', '>>por<<', '>>ita<<', '>>oci<<', '>>arg<<', '>>min<<']
+
+>>> model = MarianMTModel.from_pretrained(model_name)
+>>> translated = model.generate(**tokenizer(src_text, return_tensors="pt", padding=True))
+>>> [tokenizer.decode(t, skip_special_tokens=True) for t in translated]
+["c'est une phrase en anglais que nous voulons traduire en français",
+ 'Isto deve ir para o português.',
+ 'Y esto al español']
+```
+
+Here is the code to see all available pretrained models on the hub:
+
+```python
+from huggingface_hub import list_models
+
+model_list = list_models()
+org = "Helsinki-NLP"
+model_ids = [x.id for x in model_list if x.id.startswith(org)]
+suffix = [x.split("/")[1] for x in model_ids]
+old_style_multi_models = [f"{org}/{s}" for s in suffix if s != s.lower()]
+```
+
+## Old Style Multi-Lingual Models
+
+These are the old style multi-lingual models ported from the OPUS-MT-Train repo: and the members of each language
+group:
+
+```python no-style
+['Helsinki-NLP/opus-mt-NORTH_EU-NORTH_EU',
+ 'Helsinki-NLP/opus-mt-ROMANCE-en',
+ 'Helsinki-NLP/opus-mt-SCANDINAVIA-SCANDINAVIA',
+ 'Helsinki-NLP/opus-mt-de-ZH',
+ 'Helsinki-NLP/opus-mt-en-CELTIC',
+ 'Helsinki-NLP/opus-mt-en-ROMANCE',
+ 'Helsinki-NLP/opus-mt-es-NORWAY',
+ 'Helsinki-NLP/opus-mt-fi-NORWAY',
+ 'Helsinki-NLP/opus-mt-fi-ZH',
+ 'Helsinki-NLP/opus-mt-fi_nb_no_nn_ru_sv_en-SAMI',
+ 'Helsinki-NLP/opus-mt-sv-NORWAY',
+ 'Helsinki-NLP/opus-mt-sv-ZH']
+GROUP_MEMBERS = {
+ 'ZH': ['cmn', 'cn', 'yue', 'ze_zh', 'zh_cn', 'zh_CN', 'zh_HK', 'zh_tw', 'zh_TW', 'zh_yue', 'zhs', 'zht', 'zh'],
+ 'ROMANCE': ['fr', 'fr_BE', 'fr_CA', 'fr_FR', 'wa', 'frp', 'oc', 'ca', 'rm', 'lld', 'fur', 'lij', 'lmo', 'es', 'es_AR', 'es_CL', 'es_CO', 'es_CR', 'es_DO', 'es_EC', 'es_ES', 'es_GT', 'es_HN', 'es_MX', 'es_NI', 'es_PA', 'es_PE', 'es_PR', 'es_SV', 'es_UY', 'es_VE', 'pt', 'pt_br', 'pt_BR', 'pt_PT', 'gl', 'lad', 'an', 'mwl', 'it', 'it_IT', 'co', 'nap', 'scn', 'vec', 'sc', 'ro', 'la'],
+ 'NORTH_EU': ['de', 'nl', 'fy', 'af', 'da', 'fo', 'is', 'no', 'nb', 'nn', 'sv'],
+ 'SCANDINAVIA': ['da', 'fo', 'is', 'no', 'nb', 'nn', 'sv'],
+ 'SAMI': ['se', 'sma', 'smj', 'smn', 'sms'],
+ 'NORWAY': ['nb_NO', 'nb', 'nn_NO', 'nn', 'nog', 'no_nb', 'no'],
+ 'CELTIC': ['ga', 'cy', 'br', 'gd', 'kw', 'gv']
+}
+```
+
+Example of translating english to many romance languages, using old-style 2 character language codes
+
+
+```python
+>>> from transformers import MarianMTModel, MarianTokenizer
+
+>>> src_text = [
+... ">>fr<< this is a sentence in english that we want to translate to french",
+... ">>pt<< This should go to portuguese",
+... ">>es<< And this to Spanish",
+... ]
+
+>>> model_name = "Helsinki-NLP/opus-mt-en-ROMANCE"
+>>> tokenizer = MarianTokenizer.from_pretrained(model_name)
+
+>>> model = MarianMTModel.from_pretrained(model_name)
+>>> translated = model.generate(**tokenizer(src_text, return_tensors="pt", padding=True))
+>>> tgt_text = [tokenizer.decode(t, skip_special_tokens=True) for t in translated]
+["c'est une phrase en anglais que nous voulons traduire en français",
+ 'Isto deve ir para o português.',
+ 'Y esto al español']
+```
+
+## Resources
+
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## MarianConfig
+
+[[autodoc]] MarianConfig
+
+## MarianTokenizer
+
+[[autodoc]] MarianTokenizer
+ - build_inputs_with_special_tokens
+
+
+
+
+## MarianModel
+
+[[autodoc]] MarianModel
+ - forward
+
+## MarianMTModel
+
+[[autodoc]] MarianMTModel
+ - forward
+
+## MarianForCausalLM
+
+[[autodoc]] MarianForCausalLM
+ - forward
+
+
+
+
+## TFMarianModel
+
+[[autodoc]] TFMarianModel
+ - call
+
+## TFMarianMTModel
+
+[[autodoc]] TFMarianMTModel
+ - call
+
+
+
+
+## FlaxMarianModel
+
+[[autodoc]] FlaxMarianModel
+ - __call__
+
+## FlaxMarianMTModel
+
+[[autodoc]] FlaxMarianMTModel
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/markuplm.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/markuplm.md
new file mode 100644
index 0000000000000000000000000000000000000000..e52ff3157eac2b0a48066f9c1a3a0c0ed962e349
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/markuplm.md
@@ -0,0 +1,253 @@
+
+
+# MarkupLM
+
+## Overview
+
+The MarkupLM model was proposed in [MarkupLM: Pre-training of Text and Markup Language for Visually-rich Document
+Understanding](https://arxiv.org/abs/2110.08518) by Junlong Li, Yiheng Xu, Lei Cui, Furu Wei. MarkupLM is BERT, but
+applied to HTML pages instead of raw text documents. The model incorporates additional embedding layers to improve
+performance, similar to [LayoutLM](layoutlm).
+
+The model can be used for tasks like question answering on web pages or information extraction from web pages. It obtains
+state-of-the-art results on 2 important benchmarks:
+- [WebSRC](https://x-lance.github.io/WebSRC/), a dataset for Web-Based Structural Reading Comprehension (a bit like SQuAD but for web pages)
+- [SWDE](https://www.researchgate.net/publication/221299838_From_one_tree_to_a_forest_a_unified_solution_for_structured_web_data_extraction), a dataset
+for information extraction from web pages (basically named-entity recognition on web pages)
+
+The abstract from the paper is the following:
+
+*Multimodal pre-training with text, layout, and image has made significant progress for Visually-rich Document
+Understanding (VrDU), especially the fixed-layout documents such as scanned document images. While, there are still a
+large number of digital documents where the layout information is not fixed and needs to be interactively and
+dynamically rendered for visualization, making existing layout-based pre-training approaches not easy to apply. In this
+paper, we propose MarkupLM for document understanding tasks with markup languages as the backbone such as
+HTML/XML-based documents, where text and markup information is jointly pre-trained. Experiment results show that the
+pre-trained MarkupLM significantly outperforms the existing strong baseline models on several document understanding
+tasks. The pre-trained model and code will be publicly available.*
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found [here](https://github.com/microsoft/unilm/tree/master/markuplm).
+
+## Usage tips
+
+- In addition to `input_ids`, [`~MarkupLMModel.forward`] expects 2 additional inputs, namely `xpath_tags_seq` and `xpath_subs_seq`.
+These are the XPATH tags and subscripts respectively for each token in the input sequence.
+- One can use [`MarkupLMProcessor`] to prepare all data for the model. Refer to the [usage guide](#usage-markuplmprocessor) for more info.
+
+
+
+ MarkupLM architecture. Taken from the original paper.
+
+## Usage: MarkupLMProcessor
+
+The easiest way to prepare data for the model is to use [`MarkupLMProcessor`], which internally combines a feature extractor
+([`MarkupLMFeatureExtractor`]) and a tokenizer ([`MarkupLMTokenizer`] or [`MarkupLMTokenizerFast`]). The feature extractor is
+used to extract all nodes and xpaths from the HTML strings, which are then provided to the tokenizer, which turns them into the
+token-level inputs of the model (`input_ids` etc.). Note that you can still use the feature extractor and tokenizer separately,
+if you only want to handle one of the two tasks.
+
+```python
+from transformers import MarkupLMFeatureExtractor, MarkupLMTokenizerFast, MarkupLMProcessor
+
+feature_extractor = MarkupLMFeatureExtractor()
+tokenizer = MarkupLMTokenizerFast.from_pretrained("microsoft/markuplm-base")
+processor = MarkupLMProcessor(feature_extractor, tokenizer)
+```
+
+In short, one can provide HTML strings (and possibly additional data) to [`MarkupLMProcessor`],
+and it will create the inputs expected by the model. Internally, the processor first uses
+[`MarkupLMFeatureExtractor`] to get a list of nodes and corresponding xpaths. The nodes and
+xpaths are then provided to [`MarkupLMTokenizer`] or [`MarkupLMTokenizerFast`], which converts them
+to token-level `input_ids`, `attention_mask`, `token_type_ids`, `xpath_subs_seq`, `xpath_tags_seq`.
+Optionally, one can provide node labels to the processor, which are turned into token-level `labels`.
+
+[`MarkupLMFeatureExtractor`] uses [Beautiful Soup](https://www.crummy.com/software/BeautifulSoup/bs4/doc/), a Python library for
+pulling data out of HTML and XML files, under the hood. Note that you can still use your own parsing solution of
+choice, and provide the nodes and xpaths yourself to [`MarkupLMTokenizer`] or [`MarkupLMTokenizerFast`].
+
+In total, there are 5 use cases that are supported by the processor. Below, we list them all. Note that each of these
+use cases work for both batched and non-batched inputs (we illustrate them for non-batched inputs).
+
+**Use case 1: web page classification (training, inference) + token classification (inference), parse_html = True**
+
+This is the simplest case, in which the processor will use the feature extractor to get all nodes and xpaths from the HTML.
+
+```python
+>>> from transformers import MarkupLMProcessor
+
+>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
+
+>>> html_string = """
+...
+...
+...
+... Hello world
+...
+...
+...
Welcome
+...
Here is my website.
+...
+... """
+
+>>> # note that you can also add provide all tokenizer parameters here such as padding, truncation
+>>> encoding = processor(html_string, return_tensors="pt")
+>>> print(encoding.keys())
+dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'xpath_tags_seq', 'xpath_subs_seq'])
+```
+
+**Use case 2: web page classification (training, inference) + token classification (inference), parse_html=False**
+
+In case one already has obtained all nodes and xpaths, one doesn't need the feature extractor. In that case, one should
+provide the nodes and corresponding xpaths themselves to the processor, and make sure to set `parse_html` to `False`.
+
+```python
+>>> from transformers import MarkupLMProcessor
+
+>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
+>>> processor.parse_html = False
+
+>>> nodes = ["hello", "world", "how", "are"]
+>>> xpaths = ["/html/body/div/li[1]/div/span", "/html/body/div/li[1]/div/span", "html/body", "html/body/div"]
+>>> encoding = processor(nodes=nodes, xpaths=xpaths, return_tensors="pt")
+>>> print(encoding.keys())
+dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'xpath_tags_seq', 'xpath_subs_seq'])
+```
+
+**Use case 3: token classification (training), parse_html=False**
+
+For token classification tasks (such as [SWDE](https://paperswithcode.com/dataset/swde)), one can also provide the
+corresponding node labels in order to train a model. The processor will then convert these into token-level `labels`.
+By default, it will only label the first wordpiece of a word, and label the remaining wordpieces with -100, which is the
+`ignore_index` of PyTorch's CrossEntropyLoss. In case you want all wordpieces of a word to be labeled, you can
+initialize the tokenizer with `only_label_first_subword` set to `False`.
+
+```python
+>>> from transformers import MarkupLMProcessor
+
+>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
+>>> processor.parse_html = False
+
+>>> nodes = ["hello", "world", "how", "are"]
+>>> xpaths = ["/html/body/div/li[1]/div/span", "/html/body/div/li[1]/div/span", "html/body", "html/body/div"]
+>>> node_labels = [1, 2, 2, 1]
+>>> encoding = processor(nodes=nodes, xpaths=xpaths, node_labels=node_labels, return_tensors="pt")
+>>> print(encoding.keys())
+dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'xpath_tags_seq', 'xpath_subs_seq', 'labels'])
+```
+
+**Use case 4: web page question answering (inference), parse_html=True**
+
+For question answering tasks on web pages, you can provide a question to the processor. By default, the
+processor will use the feature extractor to get all nodes and xpaths, and create [CLS] question tokens [SEP] word tokens [SEP].
+
+```python
+>>> from transformers import MarkupLMProcessor
+
+>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
+
+>>> html_string = """
+...
+...
+...
+... Hello world
+...
+...
+...
Welcome
+...
My name is Niels.
+...
+... """
+
+>>> question = "What's his name?"
+>>> encoding = processor(html_string, questions=question, return_tensors="pt")
+>>> print(encoding.keys())
+dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'xpath_tags_seq', 'xpath_subs_seq'])
+```
+
+**Use case 5: web page question answering (inference), parse_html=False**
+
+For question answering tasks (such as WebSRC), you can provide a question to the processor. If you have extracted
+all nodes and xpaths yourself, you can provide them directly to the processor. Make sure to set `parse_html` to `False`.
+
+```python
+>>> from transformers import MarkupLMProcessor
+
+>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
+>>> processor.parse_html = False
+
+>>> nodes = ["hello", "world", "how", "are"]
+>>> xpaths = ["/html/body/div/li[1]/div/span", "/html/body/div/li[1]/div/span", "html/body", "html/body/div"]
+>>> question = "What's his name?"
+>>> encoding = processor(nodes=nodes, xpaths=xpaths, questions=question, return_tensors="pt")
+>>> print(encoding.keys())
+dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'xpath_tags_seq', 'xpath_subs_seq'])
+```
+
+## Resources
+
+- [Demo notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/MarkupLM)
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+
+## MarkupLMConfig
+
+[[autodoc]] MarkupLMConfig
+ - all
+
+## MarkupLMFeatureExtractor
+
+[[autodoc]] MarkupLMFeatureExtractor
+ - __call__
+
+## MarkupLMTokenizer
+
+[[autodoc]] MarkupLMTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## MarkupLMTokenizerFast
+
+[[autodoc]] MarkupLMTokenizerFast
+ - all
+
+## MarkupLMProcessor
+
+[[autodoc]] MarkupLMProcessor
+ - __call__
+
+## MarkupLMModel
+
+[[autodoc]] MarkupLMModel
+ - forward
+
+## MarkupLMForSequenceClassification
+
+[[autodoc]] MarkupLMForSequenceClassification
+ - forward
+
+## MarkupLMForTokenClassification
+
+[[autodoc]] MarkupLMForTokenClassification
+ - forward
+
+## MarkupLMForQuestionAnswering
+
+[[autodoc]] MarkupLMForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mask2former.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mask2former.md
new file mode 100644
index 0000000000000000000000000000000000000000..4faeed50311f69aab195c6a66504565ac903d11d
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mask2former.md
@@ -0,0 +1,76 @@
+
+
+# Mask2Former
+
+## Overview
+
+The Mask2Former model was proposed in [Masked-attention Mask Transformer for Universal Image Segmentation](https://arxiv.org/abs/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar. Mask2Former is a unified framework for panoptic, instance and semantic segmentation and features significant performance and efficiency improvements over [MaskFormer](maskformer).
+
+The abstract from the paper is the following:
+
+*Image segmentation groups pixels with different semantics, e.g., category or instance membership. Each choice
+of semantics defines a task. While only the semantics of each task differ, current research focuses on designing specialized architectures for each task. We present Masked-attention Mask Transformer (Mask2Former), a new architecture capable of addressing any image segmentation task (panoptic, instance or semantic). Its key components include masked attention, which extracts localized features by constraining cross-attention within predicted mask regions. In addition to reducing the research effort by at least three times, it outperforms the best specialized architectures by a significant margin on four popular datasets. Most notably, Mask2Former sets a new state-of-the-art for panoptic segmentation (57.8 PQ on COCO), instance segmentation (50.1 AP on COCO) and semantic segmentation (57.7 mIoU on ADE20K).*
+
+
+
+ Mask2Former architecture. Taken from the original paper.
+
+This model was contributed by [Shivalika Singh](https://huggingface.co/shivi) and [Alara Dirik](https://huggingface.co/adirik). The original code can be found [here](https://github.com/facebookresearch/Mask2Former).
+
+## Usage tips
+
+- Mask2Former uses the same preprocessing and postprocessing steps as [MaskFormer](maskformer). Use [`Mask2FormerImageProcessor`] or [`AutoImageProcessor`] to prepare images and optional targets for the model.
+- To get the final segmentation, depending on the task, you can call [`~Mask2FormerImageProcessor.post_process_semantic_segmentation`] or [`~Mask2FormerImageProcessor.post_process_instance_segmentation`] or [`~Mask2FormerImageProcessor.post_process_panoptic_segmentation`]. All three tasks can be solved using [`Mask2FormerForUniversalSegmentation`] output, panoptic segmentation accepts an optional `label_ids_to_fuse` argument to fuse instances of the target object/s (e.g. sky) together.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Mask2Former.
+
+- Demo notebooks regarding inference + fine-tuning Mask2Former on custom data can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Mask2Former).
+- Scripts for finetuning [`Mask2Former`] with [`Trainer`] or [Accelerate](https://huggingface.co/docs/accelerate/index) can be found [here](https://github.com/huggingface/transformers/tree/main/examples/pytorch/instance-segmentation).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we will review it.
+The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## Mask2FormerConfig
+
+[[autodoc]] Mask2FormerConfig
+
+## MaskFormer specific outputs
+
+[[autodoc]] models.mask2former.modeling_mask2former.Mask2FormerModelOutput
+
+[[autodoc]] models.mask2former.modeling_mask2former.Mask2FormerForUniversalSegmentationOutput
+
+## Mask2FormerModel
+
+[[autodoc]] Mask2FormerModel
+ - forward
+
+## Mask2FormerForUniversalSegmentation
+
+[[autodoc]] Mask2FormerForUniversalSegmentation
+ - forward
+
+## Mask2FormerImageProcessor
+
+[[autodoc]] Mask2FormerImageProcessor
+ - preprocess
+ - encode_inputs
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/maskformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/maskformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..a0199f380ce647e70d49d852f194bdcad5e31476
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/maskformer.md
@@ -0,0 +1,92 @@
+
+
+# MaskFormer
+
+
+
+This is a recently introduced model so the API hasn't been tested extensively. There may be some bugs or slight
+breaking changes to fix it in the future. If you see something strange, file a [Github Issue](https://github.com/huggingface/transformers/issues/new?assignees=&labels=&template=bug-report.md&title).
+
+
+
+## Overview
+
+The MaskFormer model was proposed in [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://arxiv.org/abs/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov. MaskFormer addresses semantic segmentation with a mask classification paradigm instead of performing classic pixel-level classification.
+
+The abstract from the paper is the following:
+
+*Modern approaches typically formulate semantic segmentation as a per-pixel classification task, while instance-level segmentation is handled with an alternative mask classification. Our key insight: mask classification is sufficiently general to solve both semantic- and instance-level segmentation tasks in a unified manner using the exact same model, loss, and training procedure. Following this observation, we propose MaskFormer, a simple mask classification model which predicts a set of binary masks, each associated with a single global class label prediction. Overall, the proposed mask classification-based method simplifies the landscape of effective approaches to semantic and panoptic segmentation tasks and shows excellent empirical results. In particular, we observe that MaskFormer outperforms per-pixel classification baselines when the number of classes is large. Our mask classification-based method outperforms both current state-of-the-art semantic (55.6 mIoU on ADE20K) and panoptic segmentation (52.7 PQ on COCO) models.*
+
+The figure below illustrates the architecture of MaskFormer. Taken from the [original paper](https://arxiv.org/abs/2107.06278).
+
+
+
+This model was contributed by [francesco](https://huggingface.co/francesco). The original code can be found [here](https://github.com/facebookresearch/MaskFormer).
+
+## Usage tips
+
+- MaskFormer's Transformer decoder is identical to the decoder of [DETR](detr). During training, the authors of DETR did find it helpful to use auxiliary losses in the decoder, especially to help the model output the correct number of objects of each class. If you set the parameter `use_auxiliary_loss` of [`MaskFormerConfig`] to `True`, then prediction feedforward neural networks and Hungarian losses are added after each decoder layer (with the FFNs sharing parameters).
+- If you want to train the model in a distributed environment across multiple nodes, then one should update the
+ `get_num_masks` function inside in the `MaskFormerLoss` class of `modeling_maskformer.py`. When training on multiple nodes, this should be
+ set to the average number of target masks across all nodes, as can be seen in the original implementation [here](https://github.com/facebookresearch/MaskFormer/blob/da3e60d85fdeedcb31476b5edd7d328826ce56cc/mask_former/modeling/criterion.py#L169).
+- One can use [`MaskFormerImageProcessor`] to prepare images for the model and optional targets for the model.
+- To get the final segmentation, depending on the task, you can call [`~MaskFormerImageProcessor.post_process_semantic_segmentation`] or [`~MaskFormerImageProcessor.post_process_panoptic_segmentation`]. Both tasks can be solved using [`MaskFormerForInstanceSegmentation`] output, panoptic segmentation accepts an optional `label_ids_to_fuse` argument to fuse instances of the target object/s (e.g. sky) together.
+
+## Resources
+
+
+
+- All notebooks that illustrate inference as well as fine-tuning on custom data with MaskFormer can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/MaskFormer).
+- Scripts for finetuning [`MaskFormer`] with [`Trainer`] or [Accelerate](https://huggingface.co/docs/accelerate/index) can be found [here](https://github.com/huggingface/transformers/tree/main/examples/pytorch/instance-segmentation).
+
+## MaskFormer specific outputs
+
+[[autodoc]] models.maskformer.modeling_maskformer.MaskFormerModelOutput
+
+[[autodoc]] models.maskformer.modeling_maskformer.MaskFormerForInstanceSegmentationOutput
+
+## MaskFormerConfig
+
+[[autodoc]] MaskFormerConfig
+
+## MaskFormerImageProcessor
+
+[[autodoc]] MaskFormerImageProcessor
+ - preprocess
+ - encode_inputs
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## MaskFormerFeatureExtractor
+
+[[autodoc]] MaskFormerFeatureExtractor
+ - __call__
+ - encode_inputs
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## MaskFormerModel
+
+[[autodoc]] MaskFormerModel
+ - forward
+
+## MaskFormerForInstanceSegmentation
+
+[[autodoc]] MaskFormerForInstanceSegmentation
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/matcha.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/matcha.md
new file mode 100644
index 0000000000000000000000000000000000000000..d26b88b16fae9006391fb6ae6885d9b70935fa8b
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/matcha.md
@@ -0,0 +1,76 @@
+
+
+# MatCha
+
+## Overview
+
+MatCha has been proposed in the paper [MatCha: Enhancing Visual Language Pretraining with Math Reasoning and Chart Derendering](https://arxiv.org/abs/2212.09662), from Fangyu Liu, Francesco Piccinno, Syrine Krichene, Chenxi Pang, Kenton Lee, Mandar Joshi, Yasemin Altun, Nigel Collier, Julian Martin Eisenschlos.
+
+The abstract of the paper states the following:
+
+*Visual language data such as plots, charts, and infographics are ubiquitous in the human world. However, state-of-the-art vision-language models do not perform well on these data. We propose MatCha (Math reasoning and Chart derendering pretraining) to enhance visual language models' capabilities in jointly modeling charts/plots and language data. Specifically, we propose several pretraining tasks that cover plot deconstruction and numerical reasoning which are the key capabilities in visual language modeling. We perform the MatCha pretraining starting from Pix2Struct, a recently proposed image-to-text visual language model. On standard benchmarks such as PlotQA and ChartQA, the MatCha model outperforms state-of-the-art methods by as much as nearly 20%. We also examine how well MatCha pretraining transfers to domains such as screenshots, textbook diagrams, and document figures and observe overall improvement, verifying the usefulness of MatCha pretraining on broader visual language tasks.*
+
+## Model description
+
+MatCha is a model that is trained using `Pix2Struct` architecture. You can find more information about `Pix2Struct` in the [Pix2Struct documentation](https://huggingface.co/docs/transformers/main/en/model_doc/pix2struct).
+MatCha is a Visual Question Answering subset of `Pix2Struct` architecture. It renders the input question on the image and predicts the answer.
+
+## Usage
+
+Currently 6 checkpoints are available for MatCha:
+
+- `google/matcha`: the base MatCha model, used to fine-tune MatCha on downstream tasks
+- `google/matcha-chartqa`: MatCha model fine-tuned on ChartQA dataset. It can be used to answer questions about charts.
+- `google/matcha-plotqa-v1`: MatCha model fine-tuned on PlotQA dataset. It can be used to answer questions about plots.
+- `google/matcha-plotqa-v2`: MatCha model fine-tuned on PlotQA dataset. It can be used to answer questions about plots.
+- `google/matcha-chart2text-statista`: MatCha model fine-tuned on Statista dataset.
+- `google/matcha-chart2text-pew`: MatCha model fine-tuned on Pew dataset.
+
+The models finetuned on `chart2text-pew` and `chart2text-statista` are more suited for summarization, whereas the models finetuned on `plotqa` and `chartqa` are more suited for question answering.
+
+You can use these models as follows (example on a ChatQA dataset):
+
+```python
+from transformers import AutoProcessor, Pix2StructForConditionalGeneration
+import requests
+from PIL import Image
+
+model = Pix2StructForConditionalGeneration.from_pretrained("google/matcha-chartqa").to(0)
+processor = AutoProcessor.from_pretrained("google/matcha-chartqa")
+url = "https://raw.githubusercontent.com/vis-nlp/ChartQA/main/ChartQA%20Dataset/val/png/20294671002019.png"
+image = Image.open(requests.get(url, stream=True).raw)
+
+inputs = processor(images=image, text="Is the sum of all 4 places greater than Laos?", return_tensors="pt").to(0)
+predictions = model.generate(**inputs, max_new_tokens=512)
+print(processor.decode(predictions[0], skip_special_tokens=True))
+```
+
+## Fine-tuning
+
+To fine-tune MatCha, refer to the pix2struct [fine-tuning notebook](https://github.com/huggingface/notebooks/blob/main/examples/image_captioning_pix2struct.ipynb). For `Pix2Struct` models, we have found out that fine-tuning the model with Adafactor and cosine learning rate scheduler leads to faster convergence:
+```python
+from transformers.optimization import Adafactor, get_cosine_schedule_with_warmup
+
+optimizer = Adafactor(self.parameters(), scale_parameter=False, relative_step=False, lr=0.01, weight_decay=1e-05)
+scheduler = get_cosine_schedule_with_warmup(optimizer, num_warmup_steps=1000, num_training_steps=40000)
+```
+
+
+
+MatCha is a model that is trained using `Pix2Struct` architecture. You can find more information about `Pix2Struct` in the [Pix2Struct documentation](https://huggingface.co/docs/transformers/main/en/model_doc/pix2struct).
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mbart.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mbart.md
new file mode 100644
index 0000000000000000000000000000000000000000..ca529e957e2d4aa463906a1746f1cd6511171178
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mbart.md
@@ -0,0 +1,256 @@
+
+
+# MBart and MBart-50
+
+
+
+
+## Overview of MBart
+
+The MBart model was presented in [Multilingual Denoising Pre-training for Neural Machine Translation](https://arxiv.org/abs/2001.08210) by Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov Marjan
+Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
+
+According to the abstract, MBART is a sequence-to-sequence denoising auto-encoder pretrained on large-scale monolingual
+corpora in many languages using the BART objective. mBART is one of the first methods for pretraining a complete
+sequence-to-sequence model by denoising full texts in multiple languages, while previous approaches have focused only
+on the encoder, decoder, or reconstructing parts of the text.
+
+This model was contributed by [valhalla](https://huggingface.co/valhalla). The Authors' code can be found [here](https://github.com/pytorch/fairseq/tree/master/examples/mbart)
+
+### Training of MBart
+
+MBart is a multilingual encoder-decoder (sequence-to-sequence) model primarily intended for translation task. As the
+model is multilingual it expects the sequences in a different format. A special language id token is added in both the
+source and target text. The source text format is `X [eos, src_lang_code]` where `X` is the source text. The
+target text format is `[tgt_lang_code] X [eos]`. `bos` is never used.
+
+The regular [`~MBartTokenizer.__call__`] will encode source text format passed as first argument or with the `text`
+keyword, and target text format passed with the `text_label` keyword argument.
+
+- Supervised training
+
+```python
+>>> from transformers import MBartForConditionalGeneration, MBartTokenizer
+
+>>> tokenizer = MBartTokenizer.from_pretrained("facebook/mbart-large-en-ro", src_lang="en_XX", tgt_lang="ro_RO")
+>>> example_english_phrase = "UN Chief Says There Is No Military Solution in Syria"
+>>> expected_translation_romanian = "Şeful ONU declară că nu există o soluţie militară în Siria"
+
+>>> inputs = tokenizer(example_english_phrase, text_target=expected_translation_romanian, return_tensors="pt")
+
+>>> model = MBartForConditionalGeneration.from_pretrained("facebook/mbart-large-en-ro")
+>>> # forward pass
+>>> model(**inputs)
+```
+
+- Generation
+
+ While generating the target text set the `decoder_start_token_id` to the target language id. The following
+ example shows how to translate English to Romanian using the *facebook/mbart-large-en-ro* model.
+
+```python
+>>> from transformers import MBartForConditionalGeneration, MBartTokenizer
+
+>>> tokenizer = MBartTokenizer.from_pretrained("facebook/mbart-large-en-ro", src_lang="en_XX")
+>>> article = "UN Chief Says There Is No Military Solution in Syria"
+>>> inputs = tokenizer(article, return_tensors="pt")
+>>> translated_tokens = model.generate(**inputs, decoder_start_token_id=tokenizer.lang_code_to_id["ro_RO"])
+>>> tokenizer.batch_decode(translated_tokens, skip_special_tokens=True)[0]
+"Şeful ONU declară că nu există o soluţie militară în Siria"
+```
+
+## Overview of MBart-50
+
+MBart-50 was introduced in the [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://arxiv.org/abs/2008.00401) paper by Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav
+Chaudhary, Jiatao Gu, Angela Fan. MBart-50 is created using the original *mbart-large-cc25* checkpoint by extending
+its embedding layers with randomly initialized vectors for an extra set of 25 language tokens and then pretrained on 50
+languages.
+
+According to the abstract
+
+*Multilingual translation models can be created through multilingual finetuning. Instead of finetuning on one
+direction, a pretrained model is finetuned on many directions at the same time. It demonstrates that pretrained models
+can be extended to incorporate additional languages without loss of performance. Multilingual finetuning improves on
+average 1 BLEU over the strongest baselines (being either multilingual from scratch or bilingual finetuning) while
+improving 9.3 BLEU on average over bilingual baselines from scratch.*
+
+
+### Training of MBart-50
+
+The text format for MBart-50 is slightly different from mBART. For MBart-50 the language id token is used as a prefix
+for both source and target text i.e the text format is `[lang_code] X [eos]`, where `lang_code` is source
+language id for source text and target language id for target text, with `X` being the source or target text
+respectively.
+
+
+MBart-50 has its own tokenizer [`MBart50Tokenizer`].
+
+- Supervised training
+
+```python
+from transformers import MBartForConditionalGeneration, MBart50TokenizerFast
+
+model = MBartForConditionalGeneration.from_pretrained("facebook/mbart-large-50")
+tokenizer = MBart50TokenizerFast.from_pretrained("facebook/mbart-large-50", src_lang="en_XX", tgt_lang="ro_RO")
+
+src_text = " UN Chief Says There Is No Military Solution in Syria"
+tgt_text = "Şeful ONU declară că nu există o soluţie militară în Siria"
+
+model_inputs = tokenizer(src_text, text_target=tgt_text, return_tensors="pt")
+
+model(**model_inputs) # forward pass
+```
+
+- Generation
+
+ To generate using the mBART-50 multilingual translation models, `eos_token_id` is used as the
+ `decoder_start_token_id` and the target language id is forced as the first generated token. To force the
+ target language id as the first generated token, pass the *forced_bos_token_id* parameter to the *generate* method.
+ The following example shows how to translate between Hindi to French and Arabic to English using the
+ *facebook/mbart-50-large-many-to-many* checkpoint.
+
+```python
+from transformers import MBartForConditionalGeneration, MBart50TokenizerFast
+
+article_hi = "संयुक्त राष्ट्र के प्रमुख का कहना है कि सीरिया में कोई सैन्य समाधान नहीं है"
+article_ar = "الأمين العام للأمم المتحدة يقول إنه لا يوجد حل عسكري في سوريا."
+
+model = MBartForConditionalGeneration.from_pretrained("facebook/mbart-large-50-many-to-many-mmt")
+tokenizer = MBart50TokenizerFast.from_pretrained("facebook/mbart-large-50-many-to-many-mmt")
+
+# translate Hindi to French
+tokenizer.src_lang = "hi_IN"
+encoded_hi = tokenizer(article_hi, return_tensors="pt")
+generated_tokens = model.generate(**encoded_hi, forced_bos_token_id=tokenizer.lang_code_to_id["fr_XX"])
+tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+# => "Le chef de l 'ONU affirme qu 'il n 'y a pas de solution militaire en Syria."
+
+# translate Arabic to English
+tokenizer.src_lang = "ar_AR"
+encoded_ar = tokenizer(article_ar, return_tensors="pt")
+generated_tokens = model.generate(**encoded_ar, forced_bos_token_id=tokenizer.lang_code_to_id["en_XX"])
+tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+# => "The Secretary-General of the United Nations says there is no military solution in Syria."
+```
+
+## Documentation resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## MBartConfig
+
+[[autodoc]] MBartConfig
+
+## MBartTokenizer
+
+[[autodoc]] MBartTokenizer
+ - build_inputs_with_special_tokens
+
+## MBartTokenizerFast
+
+[[autodoc]] MBartTokenizerFast
+
+## MBart50Tokenizer
+
+[[autodoc]] MBart50Tokenizer
+
+## MBart50TokenizerFast
+
+[[autodoc]] MBart50TokenizerFast
+
+
+
+
+## MBartModel
+
+[[autodoc]] MBartModel
+
+## MBartForConditionalGeneration
+
+[[autodoc]] MBartForConditionalGeneration
+
+## MBartForQuestionAnswering
+
+[[autodoc]] MBartForQuestionAnswering
+
+## MBartForSequenceClassification
+
+[[autodoc]] MBartForSequenceClassification
+
+## MBartForCausalLM
+
+[[autodoc]] MBartForCausalLM
+ - forward
+
+
+
+
+## TFMBartModel
+
+[[autodoc]] TFMBartModel
+ - call
+
+## TFMBartForConditionalGeneration
+
+[[autodoc]] TFMBartForConditionalGeneration
+ - call
+
+
+
+
+## FlaxMBartModel
+
+[[autodoc]] FlaxMBartModel
+ - __call__
+ - encode
+ - decode
+
+## FlaxMBartForConditionalGeneration
+
+[[autodoc]] FlaxMBartForConditionalGeneration
+ - __call__
+ - encode
+ - decode
+
+## FlaxMBartForSequenceClassification
+
+[[autodoc]] FlaxMBartForSequenceClassification
+ - __call__
+ - encode
+ - decode
+
+## FlaxMBartForQuestionAnswering
+
+[[autodoc]] FlaxMBartForQuestionAnswering
+ - __call__
+ - encode
+ - decode
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mctct.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mctct.md
new file mode 100644
index 0000000000000000000000000000000000000000..7cf1a68f12e4808f24798d482a5ff0a77677c470
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mctct.md
@@ -0,0 +1,79 @@
+
+
+# M-CTC-T
+
+
+
+This model is in maintenance mode only, so we won't accept any new PRs changing its code.
+
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.30.0.
+You can do so by running the following command: `pip install -U transformers==4.30.0`.
+
+
+
+## Overview
+
+The M-CTC-T model was proposed in [Pseudo-Labeling For Massively Multilingual Speech Recognition](https://arxiv.org/abs/2111.00161) by Loren Lugosch, Tatiana Likhomanenko, Gabriel Synnaeve, and Ronan Collobert. The model is a 1B-param transformer encoder, with a CTC head over 8065 character labels and a language identification head over 60 language ID labels. It is trained on Common Voice (version 6.1, December 2020 release) and VoxPopuli. After training on Common Voice and VoxPopuli, the model is trained on Common Voice only. The labels are unnormalized character-level transcripts (punctuation and capitalization are not removed). The model takes as input Mel filterbank features from a 16Khz audio signal.
+
+The abstract from the paper is the following:
+
+*Semi-supervised learning through pseudo-labeling has become a staple of state-of-the-art monolingual
+speech recognition systems. In this work, we extend pseudo-labeling to massively multilingual speech
+recognition with 60 languages. We propose a simple pseudo-labeling recipe that works well even
+with low-resource languages: train a supervised multilingual model, fine-tune it with semi-supervised
+learning on a target language, generate pseudo-labels for that language, and train a final model using
+pseudo-labels for all languages, either from scratch or by fine-tuning. Experiments on the labeled
+Common Voice and unlabeled VoxPopuli datasets show that our recipe can yield a model with better
+performance for many languages that also transfers well to LibriSpeech.*
+
+This model was contributed by [cwkeam](https://huggingface.co/cwkeam). The original code can be found [here](https://github.com/flashlight/wav2letter/tree/main/recipes/mling_pl).
+
+## Usage tips
+
+The PyTorch version of this model is only available in torch 1.9 and higher.
+
+## Resources
+
+- [Automatic speech recognition task guide](../tasks/asr)
+
+## MCTCTConfig
+
+[[autodoc]] MCTCTConfig
+
+## MCTCTFeatureExtractor
+
+[[autodoc]] MCTCTFeatureExtractor
+ - __call__
+
+## MCTCTProcessor
+
+[[autodoc]] MCTCTProcessor
+ - __call__
+ - from_pretrained
+ - save_pretrained
+ - batch_decode
+ - decode
+
+## MCTCTModel
+
+[[autodoc]] MCTCTModel
+ - forward
+
+## MCTCTForCTC
+
+[[autodoc]] MCTCTForCTC
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mega.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mega.md
new file mode 100644
index 0000000000000000000000000000000000000000..5545f5e19c47e3110451f651734878de13512aeb
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mega.md
@@ -0,0 +1,92 @@
+
+
+# MEGA
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The MEGA model was proposed in [Mega: Moving Average Equipped Gated Attention](https://arxiv.org/abs/2209.10655) by Xuezhe Ma, Chunting Zhou, Xiang Kong, Junxian He, Liangke Gui, Graham Neubig, Jonathan May, and Luke Zettlemoyer.
+MEGA proposes a new approach to self-attention with each encoder layer having a multi-headed exponential moving average in addition to a single head of standard dot-product attention, giving the attention mechanism
+stronger positional biases. This allows MEGA to perform competitively to Transformers on standard benchmarks including LRA
+while also having significantly fewer parameters. MEGA's compute efficiency allows it to scale to very long sequences, making it an
+attractive option for long-document NLP tasks.
+
+The abstract from the paper is the following:
+
+ *The design choices in the Transformer attention mechanism, including weak inductive bias and quadratic computational complexity, have limited its application for modeling long sequences. In this paper, we introduce Mega, a simple, theoretically grounded, single-head gated attention mechanism equipped with (exponential) moving average to incorporate inductive bias of position-aware local dependencies into the position-agnostic attention mechanism. We further propose a variant of Mega that offers linear time and space complexity yet yields only minimal quality loss, by efficiently splitting the whole sequence into multiple chunks with fixed length. Extensive experiments on a wide range of sequence modeling benchmarks, including the Long Range Arena, neural machine translation, auto-regressive language modeling, and image and speech classification, show that Mega achieves significant improvements over other sequence models, including variants of Transformers and recent state space models. *
+
+This model was contributed by [mnaylor](https://huggingface.co/mnaylor).
+The original code can be found [here](https://github.com/facebookresearch/mega).
+
+
+## Usage tips
+
+- MEGA can perform quite well with relatively few parameters. See Appendix D in the MEGA paper for examples of architectural specs which perform well in various settings. If using MEGA as a decoder, be sure to set `bidirectional=False` to avoid errors with default bidirectional.
+- Mega-chunk is a variant of mega that reduces time and spaces complexity from quadratic to linear. Utilize chunking with MegaConfig.use_chunking and control chunk size with MegaConfig.chunk_size
+
+
+## Implementation Notes
+
+- The original implementation of MEGA had an inconsistent expectation of attention masks for padding and causal self-attention between the softmax attention and Laplace/squared ReLU method. This implementation addresses that inconsistency.
+- The original implementation did not include token type embeddings; this implementation adds support for these, with the option controlled by MegaConfig.add_token_type_embeddings
+
+
+## MegaConfig
+
+[[autodoc]] MegaConfig
+
+## MegaModel
+
+[[autodoc]] MegaModel
+ - forward
+
+## MegaForCausalLM
+
+[[autodoc]] MegaForCausalLM
+ - forward
+
+## MegaForMaskedLM
+
+[[autodoc]] MegaForMaskedLM
+ - forward
+
+## MegaForSequenceClassification
+
+[[autodoc]] MegaForSequenceClassification
+ - forward
+
+## MegaForMultipleChoice
+
+[[autodoc]] MegaForMultipleChoice
+ - forward
+
+## MegaForTokenClassification
+
+[[autodoc]] MegaForTokenClassification
+ - forward
+
+## MegaForQuestionAnswering
+
+[[autodoc]] MegaForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/megatron-bert.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/megatron-bert.md
new file mode 100644
index 0000000000000000000000000000000000000000..67000c8b843f8a4e69ae711712d09a6ab421027c
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/megatron-bert.md
@@ -0,0 +1,141 @@
+
+
+# MegatronBERT
+
+## Overview
+
+The MegatronBERT model was proposed in [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model
+Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley,
+Jared Casper and Bryan Catanzaro.
+
+The abstract from the paper is the following:
+
+*Recent work in language modeling demonstrates that training large transformer models advances the state of the art in
+Natural Language Processing applications. However, very large models can be quite difficult to train due to memory
+constraints. In this work, we present our techniques for training very large transformer models and implement a simple,
+efficient intra-layer model parallel approach that enables training transformer models with billions of parameters. Our
+approach does not require a new compiler or library changes, is orthogonal and complimentary to pipeline model
+parallelism, and can be fully implemented with the insertion of a few communication operations in native PyTorch. We
+illustrate this approach by converging transformer based models up to 8.3 billion parameters using 512 GPUs. We sustain
+15.1 PetaFLOPs across the entire application with 76% scaling efficiency when compared to a strong single GPU baseline
+that sustains 39 TeraFLOPs, which is 30% of peak FLOPs. To demonstrate that large language models can further advance
+the state of the art (SOTA), we train an 8.3 billion parameter transformer language model similar to GPT-2 and a 3.9
+billion parameter model similar to BERT. We show that careful attention to the placement of layer normalization in
+BERT-like models is critical to achieving increased performance as the model size grows. Using the GPT-2 model we
+achieve SOTA results on the WikiText103 (10.8 compared to SOTA perplexity of 15.8) and LAMBADA (66.5% compared to SOTA
+accuracy of 63.2%) datasets. Our BERT model achieves SOTA results on the RACE dataset (90.9% compared to SOTA accuracy
+of 89.4%).*
+
+This model was contributed by [jdemouth](https://huggingface.co/jdemouth). The original code can be found [here](https://github.com/NVIDIA/Megatron-LM).
+That repository contains a multi-GPU and multi-node implementation of the Megatron Language models. In particular,
+it contains a hybrid model parallel approach using "tensor parallel" and "pipeline parallel" techniques.
+
+## Usage tips
+
+We have provided pretrained [BERT-345M](https://ngc.nvidia.com/catalog/models/nvidia:megatron_bert_345m) checkpoints
+for use to evaluate or finetuning downstream tasks.
+
+To access these checkpoints, first [sign up](https://ngc.nvidia.com/signup) for and setup the NVIDIA GPU Cloud (NGC)
+Registry CLI. Further documentation for downloading models can be found in the [NGC documentation](https://docs.nvidia.com/dgx/ngc-registry-cli-user-guide/index.html#topic_6_4_1).
+
+Alternatively, you can directly download the checkpoints using:
+
+BERT-345M-uncased:
+
+```bash
+wget --content-disposition https://api.ngc.nvidia.com/v2/models/nvidia/megatron_bert_345m/versions/v0.1_uncased/zip
+-O megatron_bert_345m_v0_1_uncased.zip
+```
+
+BERT-345M-cased:
+
+```bash
+wget --content-disposition https://api.ngc.nvidia.com/v2/models/nvidia/megatron_bert_345m/versions/v0.1_cased/zip -O
+megatron_bert_345m_v0_1_cased.zip
+```
+
+Once you have obtained the checkpoints from NVIDIA GPU Cloud (NGC), you have to convert them to a format that will
+easily be loaded by Hugging Face Transformers and our port of the BERT code.
+
+The following commands allow you to do the conversion. We assume that the folder `models/megatron_bert` contains
+`megatron_bert_345m_v0_1_{cased, uncased}.zip` and that the commands are run from inside that folder:
+
+```bash
+python3 $PATH_TO_TRANSFORMERS/models/megatron_bert/convert_megatron_bert_checkpoint.py megatron_bert_345m_v0_1_uncased.zip
+```
+
+```bash
+python3 $PATH_TO_TRANSFORMERS/models/megatron_bert/convert_megatron_bert_checkpoint.py megatron_bert_345m_v0_1_cased.zip
+```
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## MegatronBertConfig
+
+[[autodoc]] MegatronBertConfig
+
+## MegatronBertModel
+
+[[autodoc]] MegatronBertModel
+ - forward
+
+## MegatronBertForMaskedLM
+
+[[autodoc]] MegatronBertForMaskedLM
+ - forward
+
+## MegatronBertForCausalLM
+
+[[autodoc]] MegatronBertForCausalLM
+ - forward
+
+## MegatronBertForNextSentencePrediction
+
+[[autodoc]] MegatronBertForNextSentencePrediction
+ - forward
+
+## MegatronBertForPreTraining
+
+[[autodoc]] MegatronBertForPreTraining
+ - forward
+
+## MegatronBertForSequenceClassification
+
+[[autodoc]] MegatronBertForSequenceClassification
+ - forward
+
+## MegatronBertForMultipleChoice
+
+[[autodoc]] MegatronBertForMultipleChoice
+ - forward
+
+## MegatronBertForTokenClassification
+
+[[autodoc]] MegatronBertForTokenClassification
+ - forward
+
+## MegatronBertForQuestionAnswering
+
+[[autodoc]] MegatronBertForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/megatron_gpt2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/megatron_gpt2.md
new file mode 100644
index 0000000000000000000000000000000000000000..284fd372c0e068733249db26db23c1b343027ea3
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/megatron_gpt2.md
@@ -0,0 +1,77 @@
+
+
+# MegatronGPT2
+
+## Overview
+
+The MegatronGPT2 model was proposed in [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model
+Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley,
+Jared Casper and Bryan Catanzaro.
+
+The abstract from the paper is the following:
+
+*Recent work in language modeling demonstrates that training large transformer models advances the state of the art in
+Natural Language Processing applications. However, very large models can be quite difficult to train due to memory
+constraints. In this work, we present our techniques for training very large transformer models and implement a simple,
+efficient intra-layer model parallel approach that enables training transformer models with billions of parameters. Our
+approach does not require a new compiler or library changes, is orthogonal and complimentary to pipeline model
+parallelism, and can be fully implemented with the insertion of a few communication operations in native PyTorch. We
+illustrate this approach by converging transformer based models up to 8.3 billion parameters using 512 GPUs. We sustain
+15.1 PetaFLOPs across the entire application with 76% scaling efficiency when compared to a strong single GPU baseline
+that sustains 39 TeraFLOPs, which is 30% of peak FLOPs. To demonstrate that large language models can further advance
+the state of the art (SOTA), we train an 8.3 billion parameter transformer language model similar to GPT-2 and a 3.9
+billion parameter model similar to BERT. We show that careful attention to the placement of layer normalization in
+BERT-like models is critical to achieving increased performance as the model size grows. Using the GPT-2 model we
+achieve SOTA results on the WikiText103 (10.8 compared to SOTA perplexity of 15.8) and LAMBADA (66.5% compared to SOTA
+accuracy of 63.2%) datasets. Our BERT model achieves SOTA results on the RACE dataset (90.9% compared to SOTA accuracy
+of 89.4%).*
+
+This model was contributed by [jdemouth](https://huggingface.co/jdemouth). The original code can be found [here](https://github.com/NVIDIA/Megatron-LM).
+That repository contains a multi-GPU and multi-node implementation of the Megatron Language models. In particular, it
+contains a hybrid model parallel approach using "tensor parallel" and "pipeline parallel" techniques.
+
+## Usage tips
+
+We have provided pretrained [GPT2-345M](https://ngc.nvidia.com/catalog/models/nvidia:megatron_lm_345m) checkpoints
+for use to evaluate or finetuning downstream tasks.
+
+To access these checkpoints, first [sign up](https://ngc.nvidia.com/signup) for and setup the NVIDIA GPU Cloud (NGC)
+Registry CLI. Further documentation for downloading models can be found in the [NGC documentation](https://docs.nvidia.com/dgx/ngc-registry-cli-user-guide/index.html#topic_6_4_1).
+
+Alternatively, you can directly download the checkpoints using:
+
+```bash
+wget --content-disposition https://api.ngc.nvidia.com/v2/models/nvidia/megatron_lm_345m/versions/v0.0/zip -O
+megatron_gpt2_345m_v0_0.zip
+```
+
+Once you have obtained the checkpoint from NVIDIA GPU Cloud (NGC), you have to convert it to a format that will easily
+be loaded by Hugging Face Transformers GPT2 implementation.
+
+The following command allows you to do the conversion. We assume that the folder `models/megatron_gpt2` contains
+`megatron_gpt2_345m_v0_0.zip` and that the command is run from that folder:
+
+```bash
+python3 $PATH_TO_TRANSFORMERS/models/megatron_gpt2/convert_megatron_gpt2_checkpoint.py megatron_gpt2_345m_v0_0.zip
+```
+
+
+
+ MegatronGPT2 architecture is the same as OpenAI GPT-2 . Refer to [GPT-2 documentation](gpt2) for information on
+ configuration classes and their parameters.
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mgp-str.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mgp-str.md
new file mode 100644
index 0000000000000000000000000000000000000000..d4152e92b2eccb5cb87eef590f03a7de2f9e2178
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mgp-str.md
@@ -0,0 +1,88 @@
+
+
+# MGP-STR
+
+## Overview
+
+The MGP-STR model was proposed in [Multi-Granularity Prediction for Scene Text Recognition](https://arxiv.org/abs/2209.03592) by Peng Wang, Cheng Da, and Cong Yao. MGP-STR is a conceptually **simple** yet **powerful** vision Scene Text Recognition (STR) model, which is built upon the [Vision Transformer (ViT)](vit). To integrate linguistic knowledge, Multi-Granularity Prediction (MGP) strategy is proposed to inject information from the language modality into the model in an implicit way.
+
+The abstract from the paper is the following:
+
+*Scene text recognition (STR) has been an active research topic in computer vision for years. To tackle this challenging problem, numerous innovative methods have been successively proposed and incorporating linguistic knowledge into STR models has recently become a prominent trend. In this work, we first draw inspiration from the recent progress in Vision Transformer (ViT) to construct a conceptually simple yet powerful vision STR model, which is built upon ViT and outperforms previous state-of-the-art models for scene text recognition, including both pure vision models and language-augmented methods. To integrate linguistic knowledge, we further propose a Multi-Granularity Prediction strategy to inject information from the language modality into the model in an implicit way, i.e. , subword representations (BPE and WordPiece) widely-used in NLP are introduced into the output space, in addition to the conventional character level representation, while no independent language model (LM) is adopted. The resultant algorithm (termed MGP-STR) is able to push the performance envelop of STR to an even higher level. Specifically, it achieves an average recognition accuracy of 93.35% on standard benchmarks.*
+
+
+
+ MGP-STR architecture. Taken from the original paper.
+
+MGP-STR is trained on two synthetic datasets [MJSynth]((http://www.robots.ox.ac.uk/~vgg/data/text/)) (MJ) and [SynthText](http://www.robots.ox.ac.uk/~vgg/data/scenetext/) (ST) without fine-tuning on other datasets. It achieves state-of-the-art results on six standard Latin scene text benchmarks, including 3 regular text datasets (IC13, SVT, IIIT) and 3 irregular ones (IC15, SVTP, CUTE).
+This model was contributed by [yuekun](https://huggingface.co/yuekun). The original code can be found [here](https://github.com/AlibabaResearch/AdvancedLiterateMachinery/tree/main/OCR/MGP-STR).
+
+## Inference example
+
+[`MgpstrModel`] accepts images as input and generates three types of predictions, which represent textual information at different granularities.
+The three types of predictions are fused to give the final prediction result.
+
+The [`ViTImageProcessor`] class is responsible for preprocessing the input image and
+[`MgpstrTokenizer`] decodes the generated character tokens to the target string. The
+[`MgpstrProcessor`] wraps [`ViTImageProcessor`] and [`MgpstrTokenizer`]
+into a single instance to both extract the input features and decode the predicted token ids.
+
+- Step-by-step Optical Character Recognition (OCR)
+
+```py
+>>> from transformers import MgpstrProcessor, MgpstrForSceneTextRecognition
+>>> import requests
+>>> from PIL import Image
+
+>>> processor = MgpstrProcessor.from_pretrained('alibaba-damo/mgp-str-base')
+>>> model = MgpstrForSceneTextRecognition.from_pretrained('alibaba-damo/mgp-str-base')
+
+>>> # load image from the IIIT-5k dataset
+>>> url = "https://i.postimg.cc/ZKwLg2Gw/367-14.png"
+>>> image = Image.open(requests.get(url, stream=True).raw).convert("RGB")
+
+>>> pixel_values = processor(images=image, return_tensors="pt").pixel_values
+>>> outputs = model(pixel_values)
+
+>>> generated_text = processor.batch_decode(outputs.logits)['generated_text']
+```
+
+## MgpstrConfig
+
+[[autodoc]] MgpstrConfig
+
+## MgpstrTokenizer
+
+[[autodoc]] MgpstrTokenizer
+ - save_vocabulary
+
+## MgpstrProcessor
+
+[[autodoc]] MgpstrProcessor
+ - __call__
+ - batch_decode
+
+## MgpstrModel
+
+[[autodoc]] MgpstrModel
+ - forward
+
+## MgpstrForSceneTextRecognition
+
+[[autodoc]] MgpstrForSceneTextRecognition
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mimi.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mimi.md
new file mode 100644
index 0000000000000000000000000000000000000000..ad15a002da916625e5057d1b6bf1b861802510dc
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mimi.md
@@ -0,0 +1,69 @@
+
+
+# Mimi
+
+## Overview
+
+The Mimi model was proposed in [Moshi: a speech-text foundation model for real-time dialogue](https://kyutai.org/Moshi.pdf) by Alexandre Défossez, Laurent Mazaré, Manu Orsini, Amélie Royer, Patrick Pérez, Hervé Jégou, Edouard Grave and Neil Zeghidour. Mimi is a high-fidelity audio codec model developed by the Kyutai team, that combines semantic and acoustic information into audio tokens running at 12Hz and a bitrate of 1.1kbps. In other words, it can be used to map audio waveforms into “audio tokens”, known as “codebooks”.
+
+The abstract from the paper is the following:
+
+*We introduce Moshi, a speech-text foundation model and full-duplex spoken dialogue framework. Current systems for spoken dialogue rely on pipelines of independent components, namely voice activity detection, speech recognition, textual dialogue and text-to-speech. Such frameworks cannot emulate the experience of real conversations. First, their complexity induces a latency of several seconds between interactions. Second, text being the intermediate modality for dialogue, non-linguistic information that modifies meaning— such as emotion or non-speech sounds— is lost in the interaction. Finally, they rely on a segmentation into speaker turns, which does not take into account overlapping speech, interruptions and interjections. Moshi solves these independent issues altogether by casting spoken dialogue as speech-to-speech generation. Starting from a text language model backbone, Moshi generates speech as tokens from the residual quantizer of a neural audio codec, while modeling separately its own speech and that of the user into parallel streams. This allows for the removal of explicit speaker turns, and the modeling of arbitrary conversational dynamics. We moreover extend the hierarchical semantic-to-acoustic token generation of previous work to first predict time-aligned text tokens as a prefix to audio tokens. Not only this “Inner Monologue” method significantly improves the linguistic quality of generated speech, but we also illustrate how it can provide streaming speech recognition and text-to-speech. Our resulting model is the first real-time full-duplex spoken large language model, with a theoretical latency of 160ms, 200ms in practice, and is available at github.com/kyutai-labs/moshi.*
+
+Its architecture is based on [Encodec](model_doc/encodec) with several major differences:
+* it uses a much lower frame-rate.
+* it uses additional transformers for encoding and decoding for better latent contextualization
+* it uses a different quantization scheme: one codebook is dedicated to semantic projection.
+
+## Usage example
+
+Here is a quick example of how to encode and decode an audio using this model:
+
+```python
+>>> from datasets import load_dataset, Audio
+>>> from transformers import MimiModel, AutoFeatureExtractor
+>>> librispeech_dummy = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+
+>>> # load model and feature extractor
+>>> model = MimiModel.from_pretrained("kyutai/mimi")
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("kyutai/mimi")
+
+>>> # load audio sample
+>>> librispeech_dummy = librispeech_dummy.cast_column("audio", Audio(sampling_rate=feature_extractor.sampling_rate))
+>>> audio_sample = librispeech_dummy[-1]["audio"]["array"]
+>>> inputs = feature_extractor(raw_audio=audio_sample, sampling_rate=feature_extractor.sampling_rate, return_tensors="pt")
+
+>>> encoder_outputs = model.encode(inputs["input_values"], inputs["padding_mask"])
+>>> audio_values = model.decode(encoder_outputs.audio_codes, inputs["padding_mask"])[0]
+>>> # or the equivalent with a forward pass
+>>> audio_values = model(inputs["input_values"], inputs["padding_mask"]).audio_values
+```
+
+This model was contributed by [Yoach Lacombe (ylacombe)](https://huggingface.co/ylacombe).
+The original code can be found [here](https://github.com/kyutai-labs/moshi).
+
+
+## MimiConfig
+
+[[autodoc]] MimiConfig
+
+## MimiModel
+
+[[autodoc]] MimiModel
+ - decode
+ - encode
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mistral.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mistral.md
new file mode 100644
index 0000000000000000000000000000000000000000..cfa2af3678137a719af30898bc41ff94a170b548
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mistral.md
@@ -0,0 +1,239 @@
+
+
+# Mistral
+
+## Overview
+
+Mistral was introduced in the [this blogpost](https://mistral.ai/news/announcing-mistral-7b/) by Albert Jiang, Alexandre Sablayrolles, Arthur Mensch, Chris Bamford, Devendra Singh Chaplot, Diego de las Casas, Florian Bressand, Gianna Lengyel, Guillaume Lample, Lélio Renard Lavaud, Lucile Saulnier, Marie-Anne Lachaux, Pierre Stock, Teven Le Scao, Thibaut Lavril, Thomas Wang, Timothée Lacroix, William El Sayed.
+
+The introduction of the blog post says:
+
+*Mistral AI team is proud to release Mistral 7B, the most powerful language model for its size to date.*
+
+Mistral-7B is the first large language model (LLM) released by [mistral.ai](https://mistral.ai/).
+
+### Architectural details
+
+Mistral-7B is a decoder-only Transformer with the following architectural choices:
+
+- Sliding Window Attention - Trained with 8k context length and fixed cache size, with a theoretical attention span of 128K tokens
+- GQA (Grouped Query Attention) - allowing faster inference and lower cache size.
+- Byte-fallback BPE tokenizer - ensures that characters are never mapped to out of vocabulary tokens.
+
+For more details refer to the [release blog post](https://mistral.ai/news/announcing-mistral-7b/).
+
+### License
+
+`Mistral-7B` is released under the Apache 2.0 license.
+
+## Usage tips
+
+The Mistral team has released 3 checkpoints:
+
+- a base model, [Mistral-7B-v0.1](https://huggingface.co/mistralai/Mistral-7B-v0.1), which has been pre-trained to predict the next token on internet-scale data.
+- an instruction tuned model, [Mistral-7B-Instruct-v0.1](https://huggingface.co/mistralai/Mistral-7B-Instruct-v0.1), which is the base model optimized for chat purposes using supervised fine-tuning (SFT) and direct preference optimization (DPO).
+- an improved instruction tuned model, [Mistral-7B-Instruct-v0.2](https://huggingface.co/mistralai/Mistral-7B-Instruct-v0.2), which improves upon v1.
+
+The base model can be used as follows:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-v0.1", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-v0.1")
+
+>>> prompt = "My favourite condiment is"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to("cuda")
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"My favourite condiment is to ..."
+```
+
+The instruction tuned model can be used as follows:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-Instruct-v0.2", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-Instruct-v0.2")
+
+>>> messages = [
+... {"role": "user", "content": "What is your favourite condiment?"},
+... {"role": "assistant", "content": "Well, I'm quite partial to a good squeeze of fresh lemon juice. It adds just the right amount of zesty flavour to whatever I'm cooking up in the kitchen!"},
+... {"role": "user", "content": "Do you have mayonnaise recipes?"}
+... ]
+
+>>> model_inputs = tokenizer.apply_chat_template(messages, return_tensors="pt").to("cuda")
+
+>>> generated_ids = model.generate(model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"Mayonnaise can be made as follows: (...)"
+```
+
+As can be seen, the instruction-tuned model requires a [chat template](../chat_templating) to be applied to make sure the inputs are prepared in the right format.
+
+## Speeding up Mistral by using Flash Attention
+
+The code snippets above showcase inference without any optimization tricks. However, one can drastically speed up the model by leveraging [Flash Attention](../perf_train_gpu_one#flash-attention-2), which is a faster implementation of the attention mechanism used inside the model.
+
+First, make sure to install the latest version of Flash Attention 2 to include the sliding window attention feature.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Make also sure that you have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of the [flash attention repository](https://github.com/Dao-AILab/flash-attention). Make also sure to load your model in half-precision (e.g. `torch.float16`)
+
+To load and run a model using Flash Attention-2, refer to the snippet below:
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-v0.1", torch_dtype=torch.float16, attn_implementation="flash_attention_2", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-v0.1")
+
+>>> prompt = "My favourite condiment is"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to("cuda")
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"My favourite condiment is to (...)"
+```
+
+### Expected speedups
+
+Below is a expected speedup diagram that compares pure inference time between the native implementation in transformers using `mistralai/Mistral-7B-v0.1` checkpoint and the Flash Attention 2 version of the model.
+
+
+
+
+
+### Sliding window Attention
+
+The current implementation supports the sliding window attention mechanism and memory efficient cache management.
+To enable sliding window attention, just make sure to have a `flash-attn` version that is compatible with sliding window attention (`>=2.3.0`).
+
+The Flash Attention-2 model uses also a more memory efficient cache slicing mechanism - as recommended per the official implementation of Mistral model that use rolling cache mechanism we keep the cache size fixed (`self.config.sliding_window`), support batched generation only for `padding_side="left"` and use the absolute position of the current token to compute the positional embedding.
+
+## Shrinking down Mistral using quantization
+
+As the Mistral model has 7 billion parameters, that would require about 14GB of GPU RAM in half precision (float16), since each parameter is stored in 2 bytes. However, one can shrink down the size of the model using [quantization](../quantization.md). If the model is quantized to 4 bits (or half a byte per parameter),that requires only about 3.5GB of RAM.
+
+Quantizing a model is as simple as passing a `quantization_config` to the model. Below, we'll leverage the BitsAndyBytes quantization (but refer to [this page](../quantization.md) for other quantization methods):
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+>>> # specify how to quantize the model
+>>> quantization_config = BitsAndBytesConfig(
+... load_in_4bit=True,
+... bnb_4bit_quant_type="nf4",
+... bnb_4bit_compute_dtype="torch.float16",
+... )
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-Instruct-v0.2", quantization_config=True, device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-Instruct-v0.2")
+
+>>> prompt = "My favourite condiment is"
+
+>>> messages = [
+... {"role": "user", "content": "What is your favourite condiment?"},
+... {"role": "assistant", "content": "Well, I'm quite partial to a good squeeze of fresh lemon juice. It adds just the right amount of zesty flavour to whatever I'm cooking up in the kitchen!"},
+... {"role": "user", "content": "Do you have mayonnaise recipes?"}
+... ]
+
+>>> model_inputs = tokenizer.apply_chat_template(messages, return_tensors="pt").to("cuda")
+
+>>> generated_ids = model.generate(model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"The expected output"
+```
+
+This model was contributed by [Younes Belkada](https://huggingface.co/ybelkada) and [Arthur Zucker](https://huggingface.co/ArthurZ) .
+The original code can be found [here](https://github.com/mistralai/mistral-src).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Mistral. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- A demo notebook to perform supervised fine-tuning (SFT) of Mistral-7B can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/Mistral/Supervised_fine_tuning_(SFT)_of_an_LLM_using_Hugging_Face_tooling.ipynb). 🌎
+- A [blog post](https://www.philschmid.de/fine-tune-llms-in-2024-with-trl) on how to fine-tune LLMs in 2024 using Hugging Face tooling. 🌎
+- The [Alignment Handbook](https://github.com/huggingface/alignment-handbook) by Hugging Face includes scripts and recipes to perform supervised fine-tuning (SFT) and direct preference optimization with Mistral-7B. This includes scripts for full fine-tuning, QLoRa on a single GPU as well as multi-GPU fine-tuning.
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## MistralConfig
+
+[[autodoc]] MistralConfig
+
+## MistralModel
+
+[[autodoc]] MistralModel
+ - forward
+
+## MistralForCausalLM
+
+[[autodoc]] MistralForCausalLM
+ - forward
+
+## MistralForSequenceClassification
+
+[[autodoc]] MistralForSequenceClassification
+ - forward
+
+## MistralForTokenClassification
+
+[[autodoc]] MistralForTokenClassification
+ - forward
+
+## MistralForQuestionAnswering
+
+[[autodoc]] MistralForQuestionAnswering
+- forward
+
+## FlaxMistralModel
+
+[[autodoc]] FlaxMistralModel
+ - __call__
+
+## FlaxMistralForCausalLM
+
+[[autodoc]] FlaxMistralForCausalLM
+ - __call__
+
+## TFMistralModel
+
+[[autodoc]] TFMistralModel
+ - call
+
+## TFMistralForCausalLM
+
+[[autodoc]] TFMistralForCausalLM
+ - call
+
+## TFMistralForSequenceClassification
+
+[[autodoc]] TFMistralForSequenceClassification
+ - call
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mixtral.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mixtral.md
new file mode 100644
index 0000000000000000000000000000000000000000..b5451702e44a1683d68c388964c479112194b23b
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mixtral.md
@@ -0,0 +1,215 @@
+
+
+# Mixtral
+
+## Overview
+
+Mixtral-8x7B was introduced in the [Mixtral of Experts blogpost](https://mistral.ai/news/mixtral-of-experts/) by Albert Jiang, Alexandre Sablayrolles, Arthur Mensch, Chris Bamford, Devendra Singh Chaplot, Diego de las Casas, Florian Bressand, Gianna Lengyel, Guillaume Lample, Lélio Renard Lavaud, Lucile Saulnier, Marie-Anne Lachaux, Pierre Stock, Teven Le Scao, Thibaut Lavril, Thomas Wang, Timothée Lacroix, William El Sayed.
+
+The introduction of the blog post says:
+
+*Today, the team is proud to release Mixtral 8x7B, a high-quality sparse mixture of experts models (SMoE) with open weights. Licensed under Apache 2.0. Mixtral outperforms Llama 2 70B on most benchmarks with 6x faster inference. It is the strongest open-weight model with a permissive license and the best model overall regarding cost/performance trade-offs. In particular, it matches or outperforms GPT3.5 on most standard benchmarks.*
+
+Mixtral-8x7B is the second large language model (LLM) released by [mistral.ai](https://mistral.ai/), after [Mistral-7B](mistral).
+
+### Architectural details
+
+Mixtral-8x7B is a decoder-only Transformer with the following architectural choices:
+
+- Mixtral is a Mixture of Experts (MoE) model with 8 experts per MLP, with a total of 45 billion parameters. To learn more about mixture-of-experts, refer to the [blog post](https://huggingface.co/blog/moe).
+- Despite the model having 45 billion parameters, the compute required for a single forward pass is the same as that of a 14 billion parameter model. This is because even though each of the experts have to be loaded in RAM (70B like ram requirement) each token from the hidden states are dispatched twice (top 2 routing) and thus the compute (the operation required at each forward computation) is just 2 X sequence_length.
+
+The following implementation details are shared with Mistral AI's first model [Mistral-7B](mistral):
+- Sliding Window Attention - Trained with 8k context length and fixed cache size, with a theoretical attention span of 128K tokens
+- GQA (Grouped Query Attention) - allowing faster inference and lower cache size.
+- Byte-fallback BPE tokenizer - ensures that characters are never mapped to out of vocabulary tokens.
+
+For more details refer to the [release blog post](https://mistral.ai/news/mixtral-of-experts/).
+
+### License
+
+`Mixtral-8x7B` is released under the Apache 2.0 license.
+
+## Usage tips
+
+The Mistral team has released 2 checkpoints:
+- a base model, [Mixtral-8x7B-v0.1](https://huggingface.co/mistralai/Mixtral-8x7B-v0.1), which has been pre-trained to predict the next token on internet-scale data.
+- an instruction tuned model, [Mixtral-8x7B-Instruct-v0.1](https://huggingface.co/mistralai/Mixtral-8x7B-Instruct-v0.1), which is the base model optimized for chat purposes using supervised fine-tuning (SFT) and direct preference optimization (DPO).
+
+The base model can be used as follows:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mixtral-8x7B-v0.1", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mixtral-8x7B-v0.1")
+
+>>> prompt = "My favourite condiment is"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to("cuda")
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"My favourite condiment is to ..."
+```
+
+The instruction tuned model can be used as follows:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mixtral-8x7B-Instruct-v0.1", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mixtral-8x7B-Instruct-v0.1")
+
+>>> messages = [
+... {"role": "user", "content": "What is your favourite condiment?"},
+... {"role": "assistant", "content": "Well, I'm quite partial to a good squeeze of fresh lemon juice. It adds just the right amount of zesty flavour to whatever I'm cooking up in the kitchen!"},
+... {"role": "user", "content": "Do you have mayonnaise recipes?"}
+... ]
+
+>>> model_inputs = tokenizer.apply_chat_template(messages, return_tensors="pt").to("cuda")
+
+>>> generated_ids = model.generate(model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"Mayonnaise can be made as follows: (...)"
+```
+
+As can be seen, the instruction-tuned model requires a [chat template](../chat_templating) to be applied to make sure the inputs are prepared in the right format.
+
+## Speeding up Mixtral by using Flash Attention
+
+The code snippets above showcase inference without any optimization tricks. However, one can drastically speed up the model by leveraging [Flash Attention](../perf_train_gpu_one#flash-attention-2), which is a faster implementation of the attention mechanism used inside the model.
+
+First, make sure to install the latest version of Flash Attention 2 to include the sliding window attention feature.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Make also sure that you have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of the [flash attention repository](https://github.com/Dao-AILab/flash-attention). Make also sure to load your model in half-precision (e.g. `torch.float16`)
+
+To load and run a model using Flash Attention-2, refer to the snippet below:
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mixtral-8x7B-v0.1", torch_dtype=torch.float16, attn_implementation="flash_attention_2", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mixtral-8x7B-v0.1")
+
+>>> prompt = "My favourite condiment is"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to("cuda")
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"The expected output"
+```
+
+### Expected speedups
+
+Below is a expected speedup diagram that compares pure inference time between the native implementation in transformers using `mistralai/Mixtral-8x7B-v0.1` checkpoint and the Flash Attention 2 version of the model.
+
+
+
+
+
+### Sliding window Attention
+
+The current implementation supports the sliding window attention mechanism and memory efficient cache management.
+To enable sliding window attention, just make sure to have a `flash-attn` version that is compatible with sliding window attention (`>=2.3.0`).
+
+The Flash Attention-2 model uses also a more memory efficient cache slicing mechanism - as recommended per the official implementation of Mistral model that use rolling cache mechanism we keep the cache size fixed (`self.config.sliding_window`), support batched generation only for `padding_side="left"` and use the absolute position of the current token to compute the positional embedding.
+
+## Shrinking down Mixtral using quantization
+
+As the Mixtral model has 45 billion parameters, that would require about 90GB of GPU RAM in half precision (float16), since each parameter is stored in 2 bytes. However, one can shrink down the size of the model using [quantization](../quantization.md). If the model is quantized to 4 bits (or half a byte per parameter), a single A100 with 40GB of RAM is enough to fit the entire model, as in that case only about 27 GB of RAM is required.
+
+Quantizing a model is as simple as passing a `quantization_config` to the model. Below, we'll leverage the bitsandbytes quantization library (but refer to [this page](../quantization.md) for alternative quantization methods):
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+>>> # specify how to quantize the model
+>>> quantization_config = BitsAndBytesConfig(
+... load_in_4bit=True,
+... bnb_4bit_quant_type="nf4",
+... bnb_4bit_compute_dtype="torch.float16",
+... )
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mixtral-8x7B-Instruct-v0.1", quantization_config=True, device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mixtral-8x7B-Instruct-v0.1")
+
+>>> prompt = "My favourite condiment is"
+
+>>> messages = [
+... {"role": "user", "content": "What is your favourite condiment?"},
+... {"role": "assistant", "content": "Well, I'm quite partial to a good squeeze of fresh lemon juice. It adds just the right amount of zesty flavour to whatever I'm cooking up in the kitchen!"},
+... {"role": "user", "content": "Do you have mayonnaise recipes?"}
+... ]
+
+>>> model_inputs = tokenizer.apply_chat_template(messages, return_tensors="pt").to("cuda")
+
+>>> generated_ids = model.generate(model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"The expected output"
+```
+
+This model was contributed by [Younes Belkada](https://huggingface.co/ybelkada) and [Arthur Zucker](https://huggingface.co/ArthurZ) .
+The original code can be found [here](https://github.com/mistralai/mistral-src).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Mixtral. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- A demo notebook to perform supervised fine-tuning (SFT) of Mixtral-8x7B can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/Mistral/Supervised_fine_tuning_(SFT)_of_an_LLM_using_Hugging_Face_tooling.ipynb). 🌎
+- A [blog post](https://medium.com/@prakharsaxena11111/finetuning-mixtral-7bx8-6071b0ebf114) on fine-tuning Mixtral-8x7B using PEFT. 🌎
+- The [Alignment Handbook](https://github.com/huggingface/alignment-handbook) by Hugging Face includes scripts and recipes to perform supervised fine-tuning (SFT) and direct preference optimization with Mistral-7B. This includes scripts for full fine-tuning, QLoRa on a single GPU as well as multi-GPU fine-tuning.
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## MixtralConfig
+
+[[autodoc]] MixtralConfig
+
+## MixtralModel
+
+[[autodoc]] MixtralModel
+ - forward
+
+## MixtralForCausalLM
+
+[[autodoc]] MixtralForCausalLM
+ - forward
+
+## MixtralForSequenceClassification
+
+[[autodoc]] MixtralForSequenceClassification
+ - forward
+
+## MixtralForTokenClassification
+
+[[autodoc]] MixtralForTokenClassification
+ - forward
+
+## MixtralForQuestionAnswering
+[[autodoc]] MixtralForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mllama.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mllama.md
new file mode 100644
index 0000000000000000000000000000000000000000..4a6080ea2ce03a3e661c2da5e89f45fe8ce00c94
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mllama.md
@@ -0,0 +1,143 @@
+
+
+# Mllama
+
+## Overview
+
+The Llama 3.2-Vision collection of multimodal large language models (LLMs) is a collection of pretrained and instruction-tuned image reasoning generative models in 11B and 90B sizes (text \+ images in / text out). The Llama 3.2-Vision instruction-tuned models are optimized for visual recognition, image reasoning, captioning, and answering general questions about an image.
+
+**Model Architecture:** Llama 3.2-Vision is built on top of Llama 3.1 text-only model, which is an auto-regressive language model that uses an optimized transformer architecture. The tuned versions use supervised fine-tuning (SFT) and reinforcement learning with human feedback (RLHF) to align with human preferences for helpfulness and safety. To support image recognition tasks, the Llama 3.2-Vision model uses a separately trained vision adapter that integrates with the pre-trained Llama 3.1 language model. The adapter consists of a series of cross-attention layers that feed image encoder representations into the core LLM.
+
+## Usage Tips
+
+- For image+text and text inputs use `MllamaForConditionalGeneration`.
+- For text-only inputs use `MllamaForCausalLM` for generation to avoid loading vision tower.
+- Each sample can contain multiple images, and the number of images can vary between samples. The processor will pad the inputs to the maximum number of images across samples and to a maximum number of tiles within each image.
+- The text passed to the processor should have the `"<|image|>"` tokens where the images should be inserted.
+- The processor has its own `apply_chat_template` method to convert chat messages to text that can then be passed as text to the processor.
+
+
+
+
+Mllama has an extra token used as a placeholder for image positions in the text. It means that input ids and an input embedding layer will have an extra token. But since the weights for input and output embeddings are not tied, the `lm_head` layer has one less token and will fail if you want to calculate loss on image tokens or apply some logit processors. In case you are training, make sure to mask out special `"<|image|>"` tokens in the `labels` as the model should not be trained on predicting them.
+
+Otherwise if you see CUDA-side index erros when generating, use the below code to expand the `lm_head` by one more token.
+
+
+```python
+old_embeddings = model.get_output_embeddings()
+
+num_tokens = model.vocab_size + 1
+resized_embeddings = model._get_resized_lm_head(old_embeddings, new_num_tokens=num_tokens, mean_resizing=True)
+resized_embeddings.requires_grad_(old_embeddings.weight.requires_grad)
+model.set_output_embeddings(resized_embeddings)
+```
+
+
+
+## Usage Example
+
+#### Instruct model
+```python
+import requests
+import torch
+from PIL import Image
+from transformers import MllamaForConditionalGeneration, AutoProcessor
+
+model_id = "meta-llama/Llama-3.2-11B-Vision-Instruct"
+model = MllamaForConditionalGeneration.from_pretrained(model_id, device_map="auto", torch_dtype=torch.bfloat16)
+processor = AutoProcessor.from_pretrained(model_id)
+
+messages = [
+ [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What does the image show?"}
+ ]
+ }
+ ],
+]
+text = processor.apply_chat_template(messages, add_generation_prompt=True)
+
+url = "https://llava-vl.github.io/static/images/view.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+inputs = processor(text=text, images=image, return_tensors="pt").to(model.device)
+output = model.generate(**inputs, max_new_tokens=25)
+print(processor.decode(output[0]))
+```
+
+#### Base model
+```python
+import requests
+import torch
+from PIL import Image
+from transformers import MllamaForConditionalGeneration, AutoProcessor
+
+model_id = "meta-llama/Llama-3.2-11B-Vision"
+model = MllamaForConditionalGeneration.from_pretrained(model_id, device_map="auto", torch_dtype=torch.bfloat16)
+processor = AutoProcessor.from_pretrained(model_id)
+
+prompt = "<|image|>If I had to write a haiku for this one"
+url = "https://llava-vl.github.io/static/images/view.jpg"
+raw_image = Image.open(requests.get(url, stream=True).raw)
+
+inputs = processor(text=prompt, images=raw_image, return_tensors="pt").to(model.device)
+output = model.generate(**inputs, do_sample=False, max_new_tokens=25)
+print(processor.decode(output[0], skip_special_tokens=True))
+```
+
+
+## MllamaConfig
+
+[[autodoc]] MllamaConfig
+
+## MllamaProcessor
+
+[[autodoc]] MllamaProcessor
+
+
+## MllamaImageProcessor
+
+[[autodoc]] MllamaImageProcessor
+
+## MllamaForConditionalGeneration
+
+[[autodoc]] MllamaForConditionalGeneration
+ - forward
+
+## MllamaForCausalLM
+
+[[autodoc]] MllamaForCausalLM
+ - forward
+
+## MllamaTextModel
+
+[[autodoc]] MllamaTextModel
+ - forward
+
+## MllamaForCausalLM
+
+[[autodoc]] MllamaForCausalLM
+ - forward
+
+## MllamaVisionModel
+
+[[autodoc]] MllamaVisionModel
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mluke.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mluke.md
new file mode 100644
index 0000000000000000000000000000000000000000..719af76ad446b9fc9d4e5b7ee671498603c07544
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mluke.md
@@ -0,0 +1,71 @@
+
+
+# mLUKE
+
+## Overview
+
+The mLUKE model was proposed in [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://arxiv.org/abs/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka. It's a multilingual extension
+of the [LUKE model](https://arxiv.org/abs/2010.01057) trained on the basis of XLM-RoBERTa.
+
+It is based on XLM-RoBERTa and adds entity embeddings, which helps improve performance on various downstream tasks
+involving reasoning about entities such as named entity recognition, extractive question answering, relation
+classification, cloze-style knowledge completion.
+
+The abstract from the paper is the following:
+
+*Recent studies have shown that multilingual pretrained language models can be effectively improved with cross-lingual
+alignment information from Wikipedia entities. However, existing methods only exploit entity information in pretraining
+and do not explicitly use entities in downstream tasks. In this study, we explore the effectiveness of leveraging
+entity representations for downstream cross-lingual tasks. We train a multilingual language model with 24 languages
+with entity representations and show the model consistently outperforms word-based pretrained models in various
+cross-lingual transfer tasks. We also analyze the model and the key insight is that incorporating entity
+representations into the input allows us to extract more language-agnostic features. We also evaluate the model with a
+multilingual cloze prompt task with the mLAMA dataset. We show that entity-based prompt elicits correct factual
+knowledge more likely than using only word representations.*
+
+This model was contributed by [ryo0634](https://huggingface.co/ryo0634). The original code can be found [here](https://github.com/studio-ousia/luke).
+
+## Usage tips
+
+One can directly plug in the weights of mLUKE into a LUKE model, like so:
+
+```python
+from transformers import LukeModel
+
+model = LukeModel.from_pretrained("studio-ousia/mluke-base")
+```
+
+Note that mLUKE has its own tokenizer, [`MLukeTokenizer`]. You can initialize it as follows:
+
+```python
+from transformers import MLukeTokenizer
+
+tokenizer = MLukeTokenizer.from_pretrained("studio-ousia/mluke-base")
+```
+
+
+
+As mLUKE's architecture is equivalent to that of LUKE, one can refer to [LUKE's documentation page](luke) for all
+tips, code examples and notebooks.
+
+
+
+## MLukeTokenizer
+
+[[autodoc]] MLukeTokenizer
+ - __call__
+ - save_vocabulary
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mms.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mms.md
new file mode 100644
index 0000000000000000000000000000000000000000..7102b88966473f381f87ba8199de539b9680dee4
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mms.md
@@ -0,0 +1,389 @@
+
+
+# MMS
+
+## Overview
+
+The MMS model was proposed in [Scaling Speech Technology to 1,000+ Languages](https://arxiv.org/abs/2305.13516)
+by Vineel Pratap, Andros Tjandra, Bowen Shi, Paden Tomasello, Arun Babu, Sayani Kundu, Ali Elkahky, Zhaoheng Ni, Apoorv Vyas, Maryam Fazel-Zarandi, Alexei Baevski, Yossi Adi, Xiaohui Zhang, Wei-Ning Hsu, Alexis Conneau, Michael Auli
+
+The abstract from the paper is the following:
+
+*Expanding the language coverage of speech technology has the potential to improve access to information for many more people.
+However, current speech technology is restricted to about one hundred languages which is a small fraction of the over 7,000
+languages spoken around the world.
+The Massively Multilingual Speech (MMS) project increases the number of supported languages by 10-40x, depending on the task.
+The main ingredients are a new dataset based on readings of publicly available religious texts and effectively leveraging
+self-supervised learning. We built pre-trained wav2vec 2.0 models covering 1,406 languages,
+a single multilingual automatic speech recognition model for 1,107 languages, speech synthesis models
+for the same number of languages, as well as a language identification model for 4,017 languages.
+Experiments show that our multilingual speech recognition model more than halves the word error rate of
+Whisper on 54 languages of the FLEURS benchmark while being trained on a small fraction of the labeled data.*
+
+Here are the different models open sourced in the MMS project. The models and code are originally released [here](https://github.com/facebookresearch/fairseq/tree/main/examples/mms). We have add them to the `transformers` framework, making them easier to use.
+
+### Automatic Speech Recognition (ASR)
+
+The ASR model checkpoints can be found here : [mms-1b-fl102](https://huggingface.co/facebook/mms-1b-fl102), [mms-1b-l1107](https://huggingface.co/facebook/mms-1b-l1107), [mms-1b-all](https://huggingface.co/facebook/mms-1b-all). For best accuracy, use the `mms-1b-all` model.
+
+Tips:
+
+- All ASR models accept a float array corresponding to the raw waveform of the speech signal. The raw waveform should be pre-processed with [`Wav2Vec2FeatureExtractor`].
+- The models were trained using connectionist temporal classification (CTC) so the model output has to be decoded using
+ [`Wav2Vec2CTCTokenizer`].
+- You can load different language adapter weights for different languages via [`~Wav2Vec2PreTrainedModel.load_adapter`]. Language adapters only consists of roughly 2 million parameters
+ and can therefore be efficiently loaded on the fly when needed.
+
+#### Loading
+
+By default MMS loads adapter weights for English. If you want to load adapter weights of another language
+make sure to specify `target_lang=` as well as `"ignore_mismatched_sizes=True`.
+The `ignore_mismatched_sizes=True` keyword has to be passed to allow the language model head to be resized according
+to the vocabulary of the specified language.
+Similarly, the processor should be loaded with the same target language
+
+```py
+from transformers import Wav2Vec2ForCTC, AutoProcessor
+
+model_id = "facebook/mms-1b-all"
+target_lang = "fra"
+
+processor = AutoProcessor.from_pretrained(model_id, target_lang=target_lang)
+model = Wav2Vec2ForCTC.from_pretrained(model_id, target_lang=target_lang, ignore_mismatched_sizes=True)
+```
+
+
+
+You can safely ignore a warning such as:
+
+```text
+Some weights of Wav2Vec2ForCTC were not initialized from the model checkpoint at facebook/mms-1b-all and are newly initialized because the shapes did not match:
+- lm_head.bias: found shape torch.Size([154]) in the checkpoint and torch.Size([314]) in the model instantiated
+- lm_head.weight: found shape torch.Size([154, 1280]) in the checkpoint and torch.Size([314, 1280]) in the model instantiated
+You should probably TRAIN this model on a down-stream task to be able to use it for predictions and inference.
+```
+
+
+
+If you want to use the ASR pipeline, you can load your chosen target language as such:
+
+```py
+from transformers import pipeline
+
+model_id = "facebook/mms-1b-all"
+target_lang = "fra"
+
+pipe = pipeline(model=model_id, model_kwargs={"target_lang": "fra", "ignore_mismatched_sizes": True})
+```
+
+#### Inference
+
+Next, let's look at how we can run MMS in inference and change adapter layers after having called [`~PretrainedModel.from_pretrained`]
+First, we load audio data in different languages using the [Datasets](https://github.com/huggingface/datasets).
+
+```py
+from datasets import load_dataset, Audio
+
+# English
+stream_data = load_dataset("mozilla-foundation/common_voice_13_0", "en", split="test", streaming=True)
+stream_data = stream_data.cast_column("audio", Audio(sampling_rate=16000))
+en_sample = next(iter(stream_data))["audio"]["array"]
+
+# French
+stream_data = load_dataset("mozilla-foundation/common_voice_13_0", "fr", split="test", streaming=True)
+stream_data = stream_data.cast_column("audio", Audio(sampling_rate=16000))
+fr_sample = next(iter(stream_data))["audio"]["array"]
+```
+
+Next, we load the model and processor
+
+```py
+from transformers import Wav2Vec2ForCTC, AutoProcessor
+import torch
+
+model_id = "facebook/mms-1b-all"
+
+processor = AutoProcessor.from_pretrained(model_id)
+model = Wav2Vec2ForCTC.from_pretrained(model_id)
+```
+
+Now we process the audio data, pass the processed audio data to the model and transcribe the model output,
+just like we usually do for [`Wav2Vec2ForCTC`].
+
+```py
+inputs = processor(en_sample, sampling_rate=16_000, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs).logits
+
+ids = torch.argmax(outputs, dim=-1)[0]
+transcription = processor.decode(ids)
+# 'joe keton disapproved of films and buster also had reservations about the media'
+```
+
+We can now keep the same model in memory and simply switch out the language adapters by
+calling the convenient [`~Wav2Vec2ForCTC.load_adapter`] function for the model and [`~Wav2Vec2CTCTokenizer.set_target_lang`] for the tokenizer.
+We pass the target language as an input - `"fra"` for French.
+
+```py
+processor.tokenizer.set_target_lang("fra")
+model.load_adapter("fra")
+
+inputs = processor(fr_sample, sampling_rate=16_000, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs).logits
+
+ids = torch.argmax(outputs, dim=-1)[0]
+transcription = processor.decode(ids)
+# "ce dernier est volé tout au long de l'histoire romaine"
+```
+
+In the same way the language can be switched out for all other supported languages. Please have a look at:
+
+```py
+processor.tokenizer.vocab.keys()
+```
+
+to see all supported languages.
+
+To further improve performance from ASR models, language model decoding can be used. See the documentation [here](https://huggingface.co/facebook/mms-1b-all) for further details.
+
+### Speech Synthesis (TTS)
+
+MMS-TTS uses the same model architecture as VITS, which was added to 🤗 Transformers in v4.33. MMS trains a separate
+model checkpoint for each of the 1100+ languages in the project. All available checkpoints can be found on the Hugging
+Face Hub: [facebook/mms-tts](https://huggingface.co/models?sort=trending&search=facebook%2Fmms-tts), and the inference
+documentation under [VITS](https://huggingface.co/docs/transformers/main/en/model_doc/vits).
+
+#### Inference
+
+To use the MMS model, first update to the latest version of the Transformers library:
+
+```bash
+pip install --upgrade transformers accelerate
+```
+
+Since the flow-based model in VITS is non-deterministic, it is good practice to set a seed to ensure reproducibility of
+the outputs.
+
+- For languages with a Roman alphabet, such as English or French, the tokenizer can be used directly to
+pre-process the text inputs. The following code example runs a forward pass using the MMS-TTS English checkpoint:
+
+```python
+import torch
+from transformers import VitsTokenizer, VitsModel, set_seed
+
+tokenizer = VitsTokenizer.from_pretrained("facebook/mms-tts-eng")
+model = VitsModel.from_pretrained("facebook/mms-tts-eng")
+
+inputs = tokenizer(text="Hello - my dog is cute", return_tensors="pt")
+
+set_seed(555) # make deterministic
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+waveform = outputs.waveform[0]
+```
+
+The resulting waveform can be saved as a `.wav` file:
+
+```python
+import scipy
+
+scipy.io.wavfile.write("synthesized_speech.wav", rate=model.config.sampling_rate, data=waveform)
+```
+
+Or displayed in a Jupyter Notebook / Google Colab:
+
+```python
+from IPython.display import Audio
+
+Audio(waveform, rate=model.config.sampling_rate)
+```
+
+For certain languages with non-Roman alphabets, such as Arabic, Mandarin or Hindi, the [`uroman`](https://github.com/isi-nlp/uroman)
+perl package is required to pre-process the text inputs to the Roman alphabet.
+
+You can check whether you require the `uroman` package for your language by inspecting the `is_uroman` attribute of
+the pre-trained `tokenizer`:
+
+```python
+from transformers import VitsTokenizer
+
+tokenizer = VitsTokenizer.from_pretrained("facebook/mms-tts-eng")
+print(tokenizer.is_uroman)
+```
+
+If required, you should apply the uroman package to your text inputs **prior** to passing them to the `VitsTokenizer`,
+since currently the tokenizer does not support performing the pre-processing itself.
+
+To do this, first clone the uroman repository to your local machine and set the bash variable `UROMAN` to the local path:
+
+```bash
+git clone https://github.com/isi-nlp/uroman.git
+cd uroman
+export UROMAN=$(pwd)
+```
+
+You can then pre-process the text input using the following code snippet. You can either rely on using the bash variable
+`UROMAN` to point to the uroman repository, or you can pass the uroman directory as an argument to the `uromanize` function:
+
+```python
+import torch
+from transformers import VitsTokenizer, VitsModel, set_seed
+import os
+import subprocess
+
+tokenizer = VitsTokenizer.from_pretrained("facebook/mms-tts-kor")
+model = VitsModel.from_pretrained("facebook/mms-tts-kor")
+
+def uromanize(input_string, uroman_path):
+ """Convert non-Roman strings to Roman using the `uroman` perl package."""
+ script_path = os.path.join(uroman_path, "bin", "uroman.pl")
+
+ command = ["perl", script_path]
+
+ process = subprocess.Popen(command, stdin=subprocess.PIPE, stdout=subprocess.PIPE, stderr=subprocess.PIPE)
+ # Execute the perl command
+ stdout, stderr = process.communicate(input=input_string.encode())
+
+ if process.returncode != 0:
+ raise ValueError(f"Error {process.returncode}: {stderr.decode()}")
+
+ # Return the output as a string and skip the new-line character at the end
+ return stdout.decode()[:-1]
+
+text = "이봐 무슨 일이야"
+uromanized_text = uromanize(text, uroman_path=os.environ["UROMAN"])
+
+inputs = tokenizer(text=uromanized_text, return_tensors="pt")
+
+set_seed(555) # make deterministic
+with torch.no_grad():
+ outputs = model(inputs["input_ids"])
+
+waveform = outputs.waveform[0]
+```
+
+**Tips:**
+
+* The MMS-TTS checkpoints are trained on lower-cased, un-punctuated text. By default, the `VitsTokenizer` *normalizes* the inputs by removing any casing and punctuation, to avoid passing out-of-vocabulary characters to the model. Hence, the model is agnostic to casing and punctuation, so these should be avoided in the text prompt. You can disable normalisation by setting `normalize=False` in the call to the tokenizer, but this will lead to un-expected behaviour and is discouraged.
+* The speaking rate can be varied by setting the attribute `model.speaking_rate` to a chosen value. Likewise, the randomness of the noise is controlled by `model.noise_scale`:
+
+```python
+import torch
+from transformers import VitsTokenizer, VitsModel, set_seed
+
+tokenizer = VitsTokenizer.from_pretrained("facebook/mms-tts-eng")
+model = VitsModel.from_pretrained("facebook/mms-tts-eng")
+
+inputs = tokenizer(text="Hello - my dog is cute", return_tensors="pt")
+
+# make deterministic
+set_seed(555)
+
+# make speech faster and more noisy
+model.speaking_rate = 1.5
+model.noise_scale = 0.8
+
+with torch.no_grad():
+ outputs = model(**inputs)
+```
+
+### Language Identification (LID)
+
+Different LID models are available based on the number of languages they can recognize - [126](https://huggingface.co/facebook/mms-lid-126), [256](https://huggingface.co/facebook/mms-lid-256), [512](https://huggingface.co/facebook/mms-lid-512), [1024](https://huggingface.co/facebook/mms-lid-1024), [2048](https://huggingface.co/facebook/mms-lid-2048), [4017](https://huggingface.co/facebook/mms-lid-4017).
+
+#### Inference
+First, we install transformers and some other libraries
+
+```bash
+pip install torch accelerate datasets[audio]
+pip install --upgrade transformers
+````
+
+Next, we load a couple of audio samples via `datasets`. Make sure that the audio data is sampled to 16000 kHz.
+
+```py
+from datasets import load_dataset, Audio
+
+# English
+stream_data = load_dataset("mozilla-foundation/common_voice_13_0", "en", split="test", streaming=True)
+stream_data = stream_data.cast_column("audio", Audio(sampling_rate=16000))
+en_sample = next(iter(stream_data))["audio"]["array"]
+
+# Arabic
+stream_data = load_dataset("mozilla-foundation/common_voice_13_0", "ar", split="test", streaming=True)
+stream_data = stream_data.cast_column("audio", Audio(sampling_rate=16000))
+ar_sample = next(iter(stream_data))["audio"]["array"]
+```
+
+Next, we load the model and processor
+
+```py
+from transformers import Wav2Vec2ForSequenceClassification, AutoFeatureExtractor
+import torch
+
+model_id = "facebook/mms-lid-126"
+
+processor = AutoFeatureExtractor.from_pretrained(model_id)
+model = Wav2Vec2ForSequenceClassification.from_pretrained(model_id)
+```
+
+Now we process the audio data, pass the processed audio data to the model to classify it into a language, just like we usually do for Wav2Vec2 audio classification models such as [ehcalabres/wav2vec2-lg-xlsr-en-speech-emotion-recognition](https://huggingface.co/harshit345/xlsr-wav2vec-speech-emotion-recognition)
+
+```py
+# English
+inputs = processor(en_sample, sampling_rate=16_000, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs).logits
+
+lang_id = torch.argmax(outputs, dim=-1)[0].item()
+detected_lang = model.config.id2label[lang_id]
+# 'eng'
+
+# Arabic
+inputs = processor(ar_sample, sampling_rate=16_000, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs).logits
+
+lang_id = torch.argmax(outputs, dim=-1)[0].item()
+detected_lang = model.config.id2label[lang_id]
+# 'ara'
+```
+
+To see all the supported languages of a checkpoint, you can print out the language ids as follows:
+```py
+processor.id2label.values()
+```
+
+### Audio Pretrained Models
+
+Pretrained models are available for two different sizes - [300M](https://huggingface.co/facebook/mms-300m) ,
+[1Bil](https://huggingface.co/facebook/mms-1b).
+
+
+
+The MMS for ASR architecture is based on the Wav2Vec2 model, refer to [Wav2Vec2's documentation page](wav2vec2) for further
+details on how to finetune with models for various downstream tasks.
+
+MMS-TTS uses the same model architecture as VITS, refer to [VITS's documentation page](vits) for API reference.
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mobilebert.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mobilebert.md
new file mode 100644
index 0000000000000000000000000000000000000000..5c9a230d0d5c404e2b8b9ac79f3db37b9d091b1f
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mobilebert.md
@@ -0,0 +1,164 @@
+
+
+# MobileBERT
+
+## Overview
+
+The MobileBERT model was proposed in [MobileBERT: a Compact Task-Agnostic BERT for Resource-Limited Devices](https://arxiv.org/abs/2004.02984) by Zhiqing Sun, Hongkun Yu, Xiaodan Song, Renjie Liu, Yiming Yang, and Denny
+Zhou. It's a bidirectional transformer based on the BERT model, which is compressed and accelerated using several
+approaches.
+
+The abstract from the paper is the following:
+
+*Natural Language Processing (NLP) has recently achieved great success by using huge pre-trained models with hundreds
+of millions of parameters. However, these models suffer from heavy model sizes and high latency such that they cannot
+be deployed to resource-limited mobile devices. In this paper, we propose MobileBERT for compressing and accelerating
+the popular BERT model. Like the original BERT, MobileBERT is task-agnostic, that is, it can be generically applied to
+various downstream NLP tasks via simple fine-tuning. Basically, MobileBERT is a thin version of BERT_LARGE, while
+equipped with bottleneck structures and a carefully designed balance between self-attentions and feed-forward networks.
+To train MobileBERT, we first train a specially designed teacher model, an inverted-bottleneck incorporated BERT_LARGE
+model. Then, we conduct knowledge transfer from this teacher to MobileBERT. Empirical studies show that MobileBERT is
+4.3x smaller and 5.5x faster than BERT_BASE while achieving competitive results on well-known benchmarks. On the
+natural language inference tasks of GLUE, MobileBERT achieves a GLUEscore o 77.7 (0.6 lower than BERT_BASE), and 62 ms
+latency on a Pixel 4 phone. On the SQuAD v1.1/v2.0 question answering task, MobileBERT achieves a dev F1 score of
+90.0/79.2 (1.5/2.1 higher than BERT_BASE).*
+
+This model was contributed by [vshampor](https://huggingface.co/vshampor). The original code can be found [here](https://github.com/google-research/google-research/tree/master/mobilebert).
+
+## Usage tips
+
+- MobileBERT is a model with absolute position embeddings so it's usually advised to pad the inputs on the right rather
+ than the left.
+- MobileBERT is similar to BERT and therefore relies on the masked language modeling (MLM) objective. It is therefore
+ efficient at predicting masked tokens and at NLU in general, but is not optimal for text generation. Models trained
+ with a causal language modeling (CLM) objective are better in that regard.
+
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## MobileBertConfig
+
+[[autodoc]] MobileBertConfig
+
+## MobileBertTokenizer
+
+[[autodoc]] MobileBertTokenizer
+
+## MobileBertTokenizerFast
+
+[[autodoc]] MobileBertTokenizerFast
+
+## MobileBert specific outputs
+
+[[autodoc]] models.mobilebert.modeling_mobilebert.MobileBertForPreTrainingOutput
+
+[[autodoc]] models.mobilebert.modeling_tf_mobilebert.TFMobileBertForPreTrainingOutput
+
+
+
+
+## MobileBertModel
+
+[[autodoc]] MobileBertModel
+ - forward
+
+## MobileBertForPreTraining
+
+[[autodoc]] MobileBertForPreTraining
+ - forward
+
+## MobileBertForMaskedLM
+
+[[autodoc]] MobileBertForMaskedLM
+ - forward
+
+## MobileBertForNextSentencePrediction
+
+[[autodoc]] MobileBertForNextSentencePrediction
+ - forward
+
+## MobileBertForSequenceClassification
+
+[[autodoc]] MobileBertForSequenceClassification
+ - forward
+
+## MobileBertForMultipleChoice
+
+[[autodoc]] MobileBertForMultipleChoice
+ - forward
+
+## MobileBertForTokenClassification
+
+[[autodoc]] MobileBertForTokenClassification
+ - forward
+
+## MobileBertForQuestionAnswering
+
+[[autodoc]] MobileBertForQuestionAnswering
+ - forward
+
+
+
+
+## TFMobileBertModel
+
+[[autodoc]] TFMobileBertModel
+ - call
+
+## TFMobileBertForPreTraining
+
+[[autodoc]] TFMobileBertForPreTraining
+ - call
+
+## TFMobileBertForMaskedLM
+
+[[autodoc]] TFMobileBertForMaskedLM
+ - call
+
+## TFMobileBertForNextSentencePrediction
+
+[[autodoc]] TFMobileBertForNextSentencePrediction
+ - call
+
+## TFMobileBertForSequenceClassification
+
+[[autodoc]] TFMobileBertForSequenceClassification
+ - call
+
+## TFMobileBertForMultipleChoice
+
+[[autodoc]] TFMobileBertForMultipleChoice
+ - call
+
+## TFMobileBertForTokenClassification
+
+[[autodoc]] TFMobileBertForTokenClassification
+ - call
+
+## TFMobileBertForQuestionAnswering
+
+[[autodoc]] TFMobileBertForQuestionAnswering
+ - call
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mobilenet_v1.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mobilenet_v1.md
new file mode 100644
index 0000000000000000000000000000000000000000..9f68035c63c2a9827c6ced8bd98dce6a221a9106
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mobilenet_v1.md
@@ -0,0 +1,84 @@
+
+
+# MobileNet V1
+
+## Overview
+
+The MobileNet model was proposed in [MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications](https://arxiv.org/abs/1704.04861) by Andrew G. Howard, Menglong Zhu, Bo Chen, Dmitry Kalenichenko, Weijun Wang, Tobias Weyand, Marco Andreetto, Hartwig Adam.
+
+The abstract from the paper is the following:
+
+*We present a class of efficient models called MobileNets for mobile and embedded vision applications. MobileNets are based on a streamlined architecture that uses depth-wise separable convolutions to build light weight deep neural networks. We introduce two simple global hyper-parameters that efficiently trade off between latency and accuracy. These hyper-parameters allow the model builder to choose the right sized model for their application based on the constraints of the problem. We present extensive experiments on resource and accuracy tradeoffs and show strong performance compared to other popular models on ImageNet classification. We then demonstrate the effectiveness of MobileNets across a wide range of applications and use cases including object detection, finegrain classification, face attributes and large scale geo-localization.*
+
+This model was contributed by [matthijs](https://huggingface.co/Matthijs). The original code and weights can be found [here](https://github.com/tensorflow/models/blob/master/research/slim/nets/mobilenet_v1.md).
+
+## Usage tips
+
+- The checkpoints are named **mobilenet\_v1\_*depth*\_*size***, for example **mobilenet\_v1\_1.0\_224**, where **1.0** is the depth multiplier (sometimes also referred to as "alpha" or the width multiplier) and **224** is the resolution of the input images the model was trained on.
+
+- Even though the checkpoint is trained on images of specific size, the model will work on images of any size. The smallest supported image size is 32x32.
+
+- One can use [`MobileNetV1ImageProcessor`] to prepare images for the model.
+
+- The available image classification checkpoints are pre-trained on [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k) (also referred to as ILSVRC 2012, a collection of 1.3 million images and 1,000 classes). However, the model predicts 1001 classes: the 1000 classes from ImageNet plus an extra “background” class (index 0).
+
+- The original TensorFlow checkpoints use different padding rules than PyTorch, requiring the model to determine the padding amount at inference time, since this depends on the input image size. To use native PyTorch padding behavior, create a [`MobileNetV1Config`] with `tf_padding = False`.
+
+Unsupported features:
+
+- The [`MobileNetV1Model`] outputs a globally pooled version of the last hidden state. In the original model it is possible to use a 7x7 average pooling layer with stride 2 instead of global pooling. For larger inputs, this gives a pooled output that is larger than 1x1 pixel. The HuggingFace implementation does not support this.
+
+- It is currently not possible to specify an `output_stride`. For smaller output strides, the original model invokes dilated convolution to prevent the spatial resolution from being reduced further. The output stride of the HuggingFace model is always 32.
+
+- The original TensorFlow checkpoints include quantized models. We do not support these models as they include additional "FakeQuantization" operations to unquantize the weights.
+
+- It's common to extract the output from the pointwise layers at indices 5, 11, 12, 13 for downstream purposes. Using `output_hidden_states=True` returns the output from all intermediate layers. There is currently no way to limit this to specific layers.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with MobileNetV1.
+
+
+
+- [`MobileNetV1ForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## MobileNetV1Config
+
+[[autodoc]] MobileNetV1Config
+
+## MobileNetV1FeatureExtractor
+
+[[autodoc]] MobileNetV1FeatureExtractor
+ - preprocess
+
+## MobileNetV1ImageProcessor
+
+[[autodoc]] MobileNetV1ImageProcessor
+ - preprocess
+
+## MobileNetV1Model
+
+[[autodoc]] MobileNetV1Model
+ - forward
+
+## MobileNetV1ForImageClassification
+
+[[autodoc]] MobileNetV1ForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mobilenet_v2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mobilenet_v2.md
new file mode 100644
index 0000000000000000000000000000000000000000..ff22231ae0c11a8f1f0856217b2415b41dc04bb1
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mobilenet_v2.md
@@ -0,0 +1,98 @@
+
+
+# MobileNet V2
+
+## Overview
+
+The MobileNet model was proposed in [MobileNetV2: Inverted Residuals and Linear Bottlenecks](https://arxiv.org/abs/1801.04381) by Mark Sandler, Andrew Howard, Menglong Zhu, Andrey Zhmoginov, Liang-Chieh Chen.
+
+The abstract from the paper is the following:
+
+*In this paper we describe a new mobile architecture, MobileNetV2, that improves the state of the art performance of mobile models on multiple tasks and benchmarks as well as across a spectrum of different model sizes. We also describe efficient ways of applying these mobile models to object detection in a novel framework we call SSDLite. Additionally, we demonstrate how to build mobile semantic segmentation models through a reduced form of DeepLabv3 which we call Mobile DeepLabv3.*
+
+*The MobileNetV2 architecture is based on an inverted residual structure where the input and output of the residual block are thin bottleneck layers opposite to traditional residual models which use expanded representations in the input an MobileNetV2 uses lightweight depthwise convolutions to filter features in the intermediate expansion layer. Additionally, we find that it is important to remove non-linearities in the narrow layers in order to maintain representational power. We demonstrate that this improves performance and provide an intuition that led to this design. Finally, our approach allows decoupling of the input/output domains from the expressiveness of the transformation, which provides a convenient framework for further analysis. We measure our performance on Imagenet classification, COCO object detection, VOC image segmentation. We evaluate the trade-offs between accuracy, and number of operations measured by multiply-adds (MAdd), as well as the number of parameters.*
+
+This model was contributed by [matthijs](https://huggingface.co/Matthijs). The original code and weights can be found [here for the main model](https://github.com/tensorflow/models/tree/master/research/slim/nets/mobilenet) and [here for DeepLabV3+](https://github.com/tensorflow/models/tree/master/research/deeplab).
+
+## Usage tips
+
+- The checkpoints are named **mobilenet\_v2\_*depth*\_*size***, for example **mobilenet\_v2\_1.0\_224**, where **1.0** is the depth multiplier (sometimes also referred to as "alpha" or the width multiplier) and **224** is the resolution of the input images the model was trained on.
+
+- Even though the checkpoint is trained on images of specific size, the model will work on images of any size. The smallest supported image size is 32x32.
+
+- One can use [`MobileNetV2ImageProcessor`] to prepare images for the model.
+
+- The available image classification checkpoints are pre-trained on [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k) (also referred to as ILSVRC 2012, a collection of 1.3 million images and 1,000 classes). However, the model predicts 1001 classes: the 1000 classes from ImageNet plus an extra “background” class (index 0).
+
+- The segmentation model uses a [DeepLabV3+](https://arxiv.org/abs/1802.02611) head. The available semantic segmentation checkpoints are pre-trained on [PASCAL VOC](http://host.robots.ox.ac.uk/pascal/VOC/).
+
+- The original TensorFlow checkpoints use different padding rules than PyTorch, requiring the model to determine the padding amount at inference time, since this depends on the input image size. To use native PyTorch padding behavior, create a [`MobileNetV2Config`] with `tf_padding = False`.
+
+Unsupported features:
+
+- The [`MobileNetV2Model`] outputs a globally pooled version of the last hidden state. In the original model it is possible to use an average pooling layer with a fixed 7x7 window and stride 1 instead of global pooling. For inputs that are larger than the recommended image size, this gives a pooled output that is larger than 1x1. The Hugging Face implementation does not support this.
+
+- The original TensorFlow checkpoints include quantized models. We do not support these models as they include additional "FakeQuantization" operations to unquantize the weights.
+
+- It's common to extract the output from the expansion layers at indices 10 and 13, as well as the output from the final 1x1 convolution layer, for downstream purposes. Using `output_hidden_states=True` returns the output from all intermediate layers. There is currently no way to limit this to specific layers.
+
+- The DeepLabV3+ segmentation head does not use the final convolution layer from the backbone, but this layer gets computed anyway. There is currently no way to tell [`MobileNetV2Model`] up to which layer it should run.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with MobileNetV2.
+
+
+
+- [`MobileNetV2ForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+**Semantic segmentation**
+- [Semantic segmentation task guide](../tasks/semantic_segmentation)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## MobileNetV2Config
+
+[[autodoc]] MobileNetV2Config
+
+## MobileNetV2FeatureExtractor
+
+[[autodoc]] MobileNetV2FeatureExtractor
+ - preprocess
+ - post_process_semantic_segmentation
+
+## MobileNetV2ImageProcessor
+
+[[autodoc]] MobileNetV2ImageProcessor
+ - preprocess
+ - post_process_semantic_segmentation
+
+## MobileNetV2Model
+
+[[autodoc]] MobileNetV2Model
+ - forward
+
+## MobileNetV2ForImageClassification
+
+[[autodoc]] MobileNetV2ForImageClassification
+ - forward
+
+## MobileNetV2ForSemanticSegmentation
+
+[[autodoc]] MobileNetV2ForSemanticSegmentation
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mobilevit.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mobilevit.md
new file mode 100644
index 0000000000000000000000000000000000000000..e724ffa380e2f98e2f006ef9b6779bad8622e3d0
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mobilevit.md
@@ -0,0 +1,130 @@
+
+
+# MobileViT
+
+## Overview
+
+The MobileViT model was proposed in [MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer](https://arxiv.org/abs/2110.02178) by Sachin Mehta and Mohammad Rastegari. MobileViT introduces a new layer that replaces local processing in convolutions with global processing using transformers.
+
+The abstract from the paper is the following:
+
+*Light-weight convolutional neural networks (CNNs) are the de-facto for mobile vision tasks. Their spatial inductive biases allow them to learn representations with fewer parameters across different vision tasks. However, these networks are spatially local. To learn global representations, self-attention-based vision trans-formers (ViTs) have been adopted. Unlike CNNs, ViTs are heavy-weight. In this paper, we ask the following question: is it possible to combine the strengths of CNNs and ViTs to build a light-weight and low latency network for mobile vision tasks? Towards this end, we introduce MobileViT, a light-weight and general-purpose vision transformer for mobile devices. MobileViT presents a different perspective for the global processing of information with transformers, i.e., transformers as convolutions. Our results show that MobileViT significantly outperforms CNN- and ViT-based networks across different tasks and datasets. On the ImageNet-1k dataset, MobileViT achieves top-1 accuracy of 78.4% with about 6 million parameters, which is 3.2% and 6.2% more accurate than MobileNetv3 (CNN-based) and DeIT (ViT-based) for a similar number of parameters. On the MS-COCO object detection task, MobileViT is 5.7% more accurate than MobileNetv3 for a similar number of parameters.*
+
+This model was contributed by [matthijs](https://huggingface.co/Matthijs). The TensorFlow version of the model was contributed by [sayakpaul](https://huggingface.co/sayakpaul). The original code and weights can be found [here](https://github.com/apple/ml-cvnets).
+
+## Usage tips
+
+- MobileViT is more like a CNN than a Transformer model. It does not work on sequence data but on batches of images. Unlike ViT, there are no embeddings. The backbone model outputs a feature map. You can follow [this tutorial](https://keras.io/examples/vision/mobilevit) for a lightweight introduction.
+- One can use [`MobileViTImageProcessor`] to prepare images for the model. Note that if you do your own preprocessing, the pretrained checkpoints expect images to be in BGR pixel order (not RGB).
+- The available image classification checkpoints are pre-trained on [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k) (also referred to as ILSVRC 2012, a collection of 1.3 million images and 1,000 classes).
+- The segmentation model uses a [DeepLabV3](https://arxiv.org/abs/1706.05587) head. The available semantic segmentation checkpoints are pre-trained on [PASCAL VOC](http://host.robots.ox.ac.uk/pascal/VOC/).
+- As the name suggests MobileViT was designed to be performant and efficient on mobile phones. The TensorFlow versions of the MobileViT models are fully compatible with [TensorFlow Lite](https://www.tensorflow.org/lite).
+
+ You can use the following code to convert a MobileViT checkpoint (be it image classification or semantic segmentation) to generate a
+ TensorFlow Lite model:
+
+```py
+from transformers import TFMobileViTForImageClassification
+import tensorflow as tf
+
+
+model_ckpt = "apple/mobilevit-xx-small"
+model = TFMobileViTForImageClassification.from_pretrained(model_ckpt)
+
+converter = tf.lite.TFLiteConverter.from_keras_model(model)
+converter.optimizations = [tf.lite.Optimize.DEFAULT]
+converter.target_spec.supported_ops = [
+ tf.lite.OpsSet.TFLITE_BUILTINS,
+ tf.lite.OpsSet.SELECT_TF_OPS,
+]
+tflite_model = converter.convert()
+tflite_filename = model_ckpt.split("/")[-1] + ".tflite"
+with open(tflite_filename, "wb") as f:
+ f.write(tflite_model)
+```
+
+ The resulting model will be just **about an MB** making it a good fit for mobile applications where resources and network
+ bandwidth can be constrained.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with MobileViT.
+
+
+
+- [`MobileViTForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+**Semantic segmentation**
+- [Semantic segmentation task guide](../tasks/semantic_segmentation)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## MobileViTConfig
+
+[[autodoc]] MobileViTConfig
+
+## MobileViTFeatureExtractor
+
+[[autodoc]] MobileViTFeatureExtractor
+ - __call__
+ - post_process_semantic_segmentation
+
+## MobileViTImageProcessor
+
+[[autodoc]] MobileViTImageProcessor
+ - preprocess
+ - post_process_semantic_segmentation
+
+
+
+
+## MobileViTModel
+
+[[autodoc]] MobileViTModel
+ - forward
+
+## MobileViTForImageClassification
+
+[[autodoc]] MobileViTForImageClassification
+ - forward
+
+## MobileViTForSemanticSegmentation
+
+[[autodoc]] MobileViTForSemanticSegmentation
+ - forward
+
+
+
+
+## TFMobileViTModel
+
+[[autodoc]] TFMobileViTModel
+ - call
+
+## TFMobileViTForImageClassification
+
+[[autodoc]] TFMobileViTForImageClassification
+ - call
+
+## TFMobileViTForSemanticSegmentation
+
+[[autodoc]] TFMobileViTForSemanticSegmentation
+ - call
+
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mobilevitv2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mobilevitv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..c3a650fc70423c59745885c89319a27430f046cf
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mobilevitv2.md
@@ -0,0 +1,56 @@
+
+
+# MobileViTV2
+
+## Overview
+
+The MobileViTV2 model was proposed in [Separable Self-attention for Mobile Vision Transformers](https://arxiv.org/abs/2206.02680) by Sachin Mehta and Mohammad Rastegari.
+
+MobileViTV2 is the second version of MobileViT, constructed by replacing the multi-headed self-attention in MobileViT with separable self-attention.
+
+The abstract from the paper is the following:
+
+*Mobile vision transformers (MobileViT) can achieve state-of-the-art performance across several mobile vision tasks, including classification and detection. Though these models have fewer parameters, they have high latency as compared to convolutional neural network-based models. The main efficiency bottleneck in MobileViT is the multi-headed self-attention (MHA) in transformers, which requires O(k2) time complexity with respect to the number of tokens (or patches) k. Moreover, MHA requires costly operations (e.g., batch-wise matrix multiplication) for computing self-attention, impacting latency on resource-constrained devices. This paper introduces a separable self-attention method with linear complexity, i.e. O(k). A simple yet effective characteristic of the proposed method is that it uses element-wise operations for computing self-attention, making it a good choice for resource-constrained devices. The improved model, MobileViTV2, is state-of-the-art on several mobile vision tasks, including ImageNet object classification and MS-COCO object detection. With about three million parameters, MobileViTV2 achieves a top-1 accuracy of 75.6% on the ImageNet dataset, outperforming MobileViT by about 1% while running 3.2× faster on a mobile device.*
+
+This model was contributed by [shehan97](https://huggingface.co/shehan97).
+The original code can be found [here](https://github.com/apple/ml-cvnets).
+
+## Usage tips
+
+- MobileViTV2 is more like a CNN than a Transformer model. It does not work on sequence data but on batches of images. Unlike ViT, there are no embeddings. The backbone model outputs a feature map.
+- One can use [`MobileViTImageProcessor`] to prepare images for the model. Note that if you do your own preprocessing, the pretrained checkpoints expect images to be in BGR pixel order (not RGB).
+- The available image classification checkpoints are pre-trained on [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k) (also referred to as ILSVRC 2012, a collection of 1.3 million images and 1,000 classes).
+- The segmentation model uses a [DeepLabV3](https://arxiv.org/abs/1706.05587) head. The available semantic segmentation checkpoints are pre-trained on [PASCAL VOC](http://host.robots.ox.ac.uk/pascal/VOC/).
+
+## MobileViTV2Config
+
+[[autodoc]] MobileViTV2Config
+
+## MobileViTV2Model
+
+[[autodoc]] MobileViTV2Model
+ - forward
+
+## MobileViTV2ForImageClassification
+
+[[autodoc]] MobileViTV2ForImageClassification
+ - forward
+
+## MobileViTV2ForSemanticSegmentation
+
+[[autodoc]] MobileViTV2ForSemanticSegmentation
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/modernbert.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/modernbert.md
new file mode 100644
index 0000000000000000000000000000000000000000..b641d7f3f581999f155b76c5d4f3edf254a50dfe
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/modernbert.md
@@ -0,0 +1,95 @@
+
+
+# ModernBert
+
+
+
+## Overview
+
+The ModernBert model was proposed in [Smarter, Better, Faster, Longer: A Modern Bidirectional Encoder for Fast, Memory Efficient, and Long Context Finetuning and Inference](https://arxiv.org/abs/2412.13663) by Benjamin Warner, Antoine Chaffin, Benjamin Clavié, Orion Weller, Oskar Hallström, Said Taghadouini, Alexis Galalgher, Raja Bisas, Faisal Ladhak, Tom Aarsen, Nathan Cooper, Grifin Adams, Jeremy Howard and Iacopo Poli.
+
+It is a refresh of the traditional encoder architecture, as used in previous models such as [BERT](https://huggingface.co/docs/transformers/en/model_doc/bert) and [RoBERTa](https://huggingface.co/docs/transformers/en/model_doc/roberta).
+
+It builds on BERT and implements many modern architectural improvements which have been developed since its original release, such as:
+- [Rotary Positional Embeddings](https://huggingface.co/blog/designing-positional-encoding) to support sequences of up to 8192 tokens.
+- [Unpadding](https://arxiv.org/abs/2208.08124) to ensure no compute is wasted on padding tokens, speeding up processing time for batches with mixed-length sequences.
+- [GeGLU](https://arxiv.org/abs/2002.05202) Replacing the original MLP layers with GeGLU layers, shown to improve performance.
+- [Alternating Attention](https://arxiv.org/abs/2004.05150v2) where most attention layers employ a sliding window of 128 tokens, with Global Attention only used every 3 layers.
+- [Flash Attention](https://github.com/Dao-AILab/flash-attention) to speed up processing.
+- A model designed following recent [The Case for Co-Designing Model Architectures with Hardware](https://arxiv.org/abs/2401.14489), ensuring maximum efficiency across inference GPUs.
+- Modern training data scales (2 trillion tokens) and mixtures (including code ande math data)
+
+The abstract from the paper is the following:
+
+*Encoder-only transformer models such as BERT offer a great performance-size tradeoff for retrieval and classification tasks with respect to larger decoder-only models. Despite being the workhorse of numerous production pipelines, there have been limited Pareto improvements to BERT since its release. In this paper, we introduce ModernBERT, bringing modern model optimizations to encoder-only models and representing a major Pareto improvement over older encoders. Trained on 2 trillion tokens with a native 8192 sequence length, ModernBERT models exhibit state-of-the-art results on a large pool of evaluations encompassing diverse classification tasks and both single and multi-vector retrieval on different domains (including code). In addition to strong downstream performance, ModernBERT is also the most speed and memory efficient encoder and is designed for inference on common GPUs.*
+
+The original code can be found [here](https://github.com/answerdotai/modernbert).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with ModernBert.
+
+
+
+- A notebook on how to [finetune for General Language Understanding Evaluation (GLUE) with Transformers](https://github.com/AnswerDotAI/ModernBERT/blob/main/examples/finetune_modernbert_on_glue.ipynb), also available as a Google Colab [notebook](https://colab.research.google.com/github/AnswerDotAI/ModernBERT/blob/main/examples/finetune_modernbert_on_glue.ipynb). 🌎
+
+
+
+- A script on how to [finetune for text similarity or information retrieval with Sentence Transformers](https://github.com/AnswerDotAI/ModernBERT/blob/main/examples/train_st.py). 🌎
+- A script on how to [finetune for information retrieval with PyLate](https://github.com/AnswerDotAI/ModernBERT/blob/main/examples/train_pylate.py). 🌎
+
+
+
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+
+
+## ModernBertConfig
+
+[[autodoc]] ModernBertConfig
+
+
+
+
+## ModernBertModel
+
+[[autodoc]] ModernBertModel
+ - forward
+
+## ModernBertForMaskedLM
+
+[[autodoc]] ModernBertForMaskedLM
+ - forward
+
+## ModernBertForSequenceClassification
+
+[[autodoc]] ModernBertForSequenceClassification
+ - forward
+
+## ModernBertForTokenClassification
+
+[[autodoc]] ModernBertForTokenClassification
+ - forward
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/moshi.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/moshi.md
new file mode 100644
index 0000000000000000000000000000000000000000..64216f570e3ed01b4e45ab788c6b56f19af69058
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/moshi.md
@@ -0,0 +1,183 @@
+
+
+# Moshi
+
+## Overview
+
+The Moshi model was proposed in [Moshi: a speech-text foundation model for real-time dialogue](https://kyutai.org/Moshi.pdf) by Alexandre Défossez, Laurent Mazaré, Manu Orsini, Amélie Royer, Patrick Pérez, Hervé Jégou, Edouard Grave and Neil Zeghidour.
+
+Moshi is a speech-text foundation model that casts spoken dialogue as speech-to-speech generation. Starting from a text language model backbone, Moshi generates speech as tokens from the residual quantizer of a neural audio codec, while modeling separately its own speech and that of the user into parallel streams. This allows for the removal of explicit speaker turns, and the modeling of arbitrary conversational dynamics. Moshi also predicts time-aligned text tokens as a prefix to audio tokens. This “Inner Monologue” method significantly improves the linguistic quality of generated speech and provides streaming speech recognition and text-to-speech. As a result, Moshi is the first real-time full-duplex spoken large language model, with a theoretical latency of 160ms, 200ms in practice.
+
+
+
+
+
+The abstract from the paper is the following:
+
+*We introduce Moshi, a speech-text foundation model and full-duplex spoken dialogue framework. Current systems for spoken dialogue rely on pipelines of independent components, namely voice activity detection, speech recognition, textual dialogue and text-to-speech. Such frameworks cannot emulate the experience of real conversations. First, their complexity induces a latency of several seconds between interactions. Second, text being the intermediate modality for dialogue, non-linguistic information that modifies meaning— such as emotion or non-speech sounds— is lost in the interaction. Finally, they rely on a segmentation into speaker turns, which does not take into account overlapping speech, interruptions and interjections. Moshi solves these independent issues altogether by casting spoken dialogue as speech-to-speech generation. Starting from a text language model backbone, Moshi generates speech as tokens from the residual quantizer of a neural audio codec, while modeling separately its own speech and that of the user into parallel streams. This allows for the removal of explicit speaker turns, and the modeling of arbitrary conversational dynamics. We moreover extend the hierarchical semantic-to-acoustic token generation of previous work to first predict time-aligned text tokens as a prefix to audio tokens. Not only this “Inner Monologue” method significantly improves the linguistic quality of generated speech, but we also illustrate how it can provide streaming speech recognition and text-to-speech. Our resulting model is the first real-time full-duplex spoken large language model, with a theoretical latency of 160ms, 200ms in practice, and is available at github.com/kyutai-labs/moshi.*
+
+Moshi deals with 3 streams of information:
+1. The user's audio
+2. Moshi's audio
+3. Moshi's textual output
+
+Similarly to [`~MusicgenModel`], audio is represented with audio codebooks, which can be interpreted like tokens. The main difference between text tokens and audio codebooks is that audio codebooks introduce an additional dimension of information.
+Text tokens are typically of dim `(batch_size, sequence_length)` but audio tokens are of dim `(batch_size, num_codebooks, sequence_length)`.
+
+Moshi's made of 3 components:
+
+**1. The main decoder (Helium in the paper)**
+
+It corresponds to [`MoshiForCausalLM`]. It is strictly a classic text LLM, that uses an architecture similar to [` ~GemmaForCausalLM`]. In other words, it takes text tokens, embeds them, pass them through the decoder and a language head, to get text logits.
+
+**2. The depth decoder**
+
+On its own, it's also a classic LLM, but this time, instead of generating over the time dimension, it generates over the codebook dimension.
+
+It also means that its context length is `num_codebooks`, thus it can't generate more than `num_codebooks`.
+
+Note that each timestamp - i.e each codebook - gets its own set of Linear Layers and Embeddings.
+
+**3. [`MimiModel`]**
+
+It's the audio encoder from Kyutai, that has recently been integrated to transformers, which is used to "tokenize" audio. It has the same use that [`~EncodecModel`] has in [`~MusicgenModel`].
+
+
+## Tips:
+
+The original checkpoints can be converted using the conversion script `src/transformers/models/moshi/convert_moshi_transformers.py`
+
+
+### How to use the model:
+
+This implementation has two main aims:
+1. quickly test model generation by simplifying the original API
+2. simplify training. A training guide will come soon, but user contributions are welcomed!
+
+
+
+It is designed for intermediate use. We strongly recommend using the original [implementation](https://github.com/kyutai-labs/moshi) to infer the model in real-time streaming.
+
+
+
+**1. Model generation**
+
+Moshi is a streaming auto-regressive model with two streams of audio. To put it differently, one audio stream corresponds to what the model said/will say and the other audio stream corresponds to what the user said/will say.
+
+[`MoshiForConditionalGeneration.generate`] thus needs 3 inputs:
+1. `input_ids` - corresponding to the text token history
+2. `moshi_input_values` or `moshi_audio_codes`- corresponding to the model audio history
+3. `user_input_values` or `user_audio_codes` - corresponding to the user audio history
+
+These three inputs must be synchronized. Meaning that their lengths must correspond to the same number of tokens.
+
+You can dynamically use the 3 inputs depending on what you want to test:
+1. Simply check the model response to an user prompt - in that case, `input_ids` can be filled with pad tokens and `user_input_values` can be a zero tensor of the same shape than the user prompt.
+2. Test more complex behaviour - in that case, you must be careful about how the input tokens are synchronized with the audios.
+
+
+
+The original model is synchronized text with audio by padding the text in between each token enunciation.
+
+To follow the example of the following image, `"Hello, I'm Moshi"` could be transformed to `"Hello,I'm Moshi"`.
+
+
+
+
+
+
+
+
+[`MoshiForConditionalGeneration.generate`] then auto-regressively feeds to itself its own audio stream, but since it doesn't have access to the user input stream while using `transformers`, it will thus **assume that the user is producing blank audio**.
+
+
+
+```python
+>>> from datasets import load_dataset, Audio
+>>> import torch, math
+>>> from transformers import MoshiForConditionalGeneration, AutoFeatureExtractor, AutoTokenizer
+>>> librispeech_dummy = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+
+
+>>> # prepare user input audio
+>>> librispeech_dummy = librispeech_dummy.cast_column("audio", Audio(sampling_rate=feature_extractor.sampling_rate))
+>>> audio_sample = librispeech_dummy[-1]["audio"]["array"]
+>>> user_input_values = feature_extractor(raw_audio=audio_sample, sampling_rate=feature_extractor.sampling_rate, return_tensors="pt").to(device=device, dtype=dtype)
+
+>>> # prepare moshi input values - we suppose moshi didn't say anything while the user spoke
+>>> moshi_input_values = torch.zeros_like(user_input_values.input_values)
+
+>>> # prepare moshi input ids - we suppose moshi didn't say anything while the user spoke
+>>> num_tokens = math.ceil(moshi_input_values.shape[-1] * waveform_to_token_ratio)
+>>> input_ids = torch.ones((1, num_tokens), device=device, dtype=torch.int64) * tokenizer.encode("")[0]
+
+>>> # generate 25 new tokens (around 2s of audio)
+>>> output = model.generate(input_ids=input_ids, user_input_values=user_input_values.input_values, moshi_input_values=moshi_input_values, max_new_tokens=25)
+
+>>> text_tokens = output.sequences
+>>> audio_waveforms = output.audio_sequences
+```
+
+**2. Model training**
+
+Most of the work has to be done during data creation/pre-processing, because of the need to align/synchronize streams.
+
+Once it's done, you can simply forward `text_labels` and `audio_labels` to [`MoshiForConditionalGeneration.forward`], alongside the usual inputs, to get the model loss.
+
+A training guide will come soon, but user contributions are welcomed!
+
+### How does the model forward the inputs / generate:
+
+1. The input streams are embedded and combined into `inputs_embeds`.
+
+2. `inputs_embeds` is passed through the main decoder, which processes it like a normal LLM would.
+
+3. The main decoder outputs `text logits` but also its `last hidden state` which is called `temporal context` in the paper.
+
+3. The depth decoder switches the dimension on which we forward / generate (codebooks instead of time). It uses the token generated from `text logits` and the `temporal context` to auto-regressively generate audio codebooks.
+
+
+This model was contributed by [Yoach Lacombe (ylacombe)](https://huggingface.co/ylacombe).
+
+The original code can be found [here](https://github.com/kyutai-labs/moshi).
+
+
+
+## MoshiConfig
+
+[[autodoc]] MoshiConfig
+
+## MoshiDepthConfig
+
+[[autodoc]] MoshiDepthConfig
+
+## MoshiModel
+
+[[autodoc]] MoshiModel
+ - forward
+
+## MoshiForCausalLM
+
+[[autodoc]] MoshiForCausalLM
+ - forward
+
+## MoshiForConditionalGeneration
+
+[[autodoc]] MoshiForConditionalGeneration
+ - forward
+ - generate
+ - get_unconditional_inputs
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mpnet.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mpnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..c571da47b0048cc8087c2f52edd5771d1e30fb8f
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mpnet.md
@@ -0,0 +1,138 @@
+
+
+# MPNet
+
+## Overview
+
+The MPNet model was proposed in [MPNet: Masked and Permuted Pre-training for Language Understanding](https://arxiv.org/abs/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
+
+MPNet adopts a novel pre-training method, named masked and permuted language modeling, to inherit the advantages of
+masked language modeling and permuted language modeling for natural language understanding.
+
+The abstract from the paper is the following:
+
+*BERT adopts masked language modeling (MLM) for pre-training and is one of the most successful pre-training models.
+Since BERT neglects dependency among predicted tokens, XLNet introduces permuted language modeling (PLM) for
+pre-training to address this problem. However, XLNet does not leverage the full position information of a sentence and
+thus suffers from position discrepancy between pre-training and fine-tuning. In this paper, we propose MPNet, a novel
+pre-training method that inherits the advantages of BERT and XLNet and avoids their limitations. MPNet leverages the
+dependency among predicted tokens through permuted language modeling (vs. MLM in BERT), and takes auxiliary position
+information as input to make the model see a full sentence and thus reducing the position discrepancy (vs. PLM in
+XLNet). We pre-train MPNet on a large-scale dataset (over 160GB text corpora) and fine-tune on a variety of
+down-streaming tasks (GLUE, SQuAD, etc). Experimental results show that MPNet outperforms MLM and PLM by a large
+margin, and achieves better results on these tasks compared with previous state-of-the-art pre-trained methods (e.g.,
+BERT, XLNet, RoBERTa) under the same model setting.*
+
+The original code can be found [here](https://github.com/microsoft/MPNet).
+
+## Usage tips
+
+MPNet doesn't have `token_type_ids`, you don't need to indicate which token belongs to which segment. Just
+separate your segments with the separation token `tokenizer.sep_token` (or `[sep]`).
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## MPNetConfig
+
+[[autodoc]] MPNetConfig
+
+## MPNetTokenizer
+
+[[autodoc]] MPNetTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## MPNetTokenizerFast
+
+[[autodoc]] MPNetTokenizerFast
+
+
+
+
+## MPNetModel
+
+[[autodoc]] MPNetModel
+ - forward
+
+## MPNetForMaskedLM
+
+[[autodoc]] MPNetForMaskedLM
+ - forward
+
+## MPNetForSequenceClassification
+
+[[autodoc]] MPNetForSequenceClassification
+ - forward
+
+## MPNetForMultipleChoice
+
+[[autodoc]] MPNetForMultipleChoice
+ - forward
+
+## MPNetForTokenClassification
+
+[[autodoc]] MPNetForTokenClassification
+ - forward
+
+## MPNetForQuestionAnswering
+
+[[autodoc]] MPNetForQuestionAnswering
+ - forward
+
+
+
+
+## TFMPNetModel
+
+[[autodoc]] TFMPNetModel
+ - call
+
+## TFMPNetForMaskedLM
+
+[[autodoc]] TFMPNetForMaskedLM
+ - call
+
+## TFMPNetForSequenceClassification
+
+[[autodoc]] TFMPNetForSequenceClassification
+ - call
+
+## TFMPNetForMultipleChoice
+
+[[autodoc]] TFMPNetForMultipleChoice
+ - call
+
+## TFMPNetForTokenClassification
+
+[[autodoc]] TFMPNetForTokenClassification
+ - call
+
+## TFMPNetForQuestionAnswering
+
+[[autodoc]] TFMPNetForQuestionAnswering
+ - call
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mpt.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mpt.md
new file mode 100644
index 0000000000000000000000000000000000000000..113b42573f4db1e9e5c04d1af2baa20a39d059a4
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mpt.md
@@ -0,0 +1,70 @@
+
+
+# MPT
+
+## Overview
+
+The MPT model was proposed by the [MosaicML](https://www.mosaicml.com/) team and released with multiple sizes and finetuned variants. The MPT models are a series of open source and commercially usable LLMs pre-trained on 1T tokens.
+
+MPT models are GPT-style decoder-only transformers with several improvements: performance-optimized layer implementations, architecture changes that provide greater training stability, and the elimination of context length limits by replacing positional embeddings with ALiBi.
+
+- MPT base: MPT base pre-trained models on next token prediction
+- MPT instruct: MPT base models fine-tuned on instruction based tasks
+- MPT storywriter: MPT base models fine-tuned for 2500 steps on 65k-token excerpts of fiction books contained in the books3 corpus, this enables the model to handle very long sequences
+
+The original code is available at the [`llm-foundry`](https://github.com/mosaicml/llm-foundry/tree/main) repository.
+
+Read more about it [in the release blogpost](https://www.mosaicml.com/blog/mpt-7b)
+
+## Usage tips
+
+- Learn more about some techniques behind training of the model [in this section of llm-foundry repository](https://github.com/mosaicml/llm-foundry/blob/main/TUTORIAL.md#faqs)
+- If you want to use the advanced version of the model (triton kernels, direct flash attention integration), you can still use the original model implementation by adding `trust_remote_code=True` when calling `from_pretrained`.
+
+## Resources
+
+- [Fine-tuning Notebook](https://colab.research.google.com/drive/1HCpQkLL7UXW8xJUJJ29X7QAeNJKO0frZ?usp=sharing) on how to fine-tune MPT-7B on a free Google Colab instance to turn the model into a Chatbot.
+
+## MptConfig
+
+[[autodoc]] MptConfig
+ - all
+
+## MptModel
+
+[[autodoc]] MptModel
+ - forward
+
+## MptForCausalLM
+
+[[autodoc]] MptForCausalLM
+ - forward
+
+## MptForSequenceClassification
+
+[[autodoc]] MptForSequenceClassification
+ - forward
+
+## MptForTokenClassification
+
+[[autodoc]] MptForTokenClassification
+ - forward
+
+## MptForQuestionAnswering
+
+[[autodoc]] MptForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mra.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mra.md
new file mode 100644
index 0000000000000000000000000000000000000000..cc4c0d9cc9c8344d349ab6ea3783337786d3174c
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mra.md
@@ -0,0 +1,62 @@
+
+
+# MRA
+
+## Overview
+
+The MRA model was proposed in [Multi Resolution Analysis (MRA) for Approximate Self-Attention](https://arxiv.org/abs/2207.10284) by Zhanpeng Zeng, Sourav Pal, Jeffery Kline, Glenn M Fung, and Vikas Singh.
+
+The abstract from the paper is the following:
+
+*Transformers have emerged as a preferred model for many tasks in natural language processing and vision. Recent efforts on training and deploying Transformers more efficiently have identified many strategies to approximate the self-attention matrix, a key module in a Transformer architecture. Effective ideas include various prespecified sparsity patterns, low-rank basis expansions and combinations thereof. In this paper, we revisit classical Multiresolution Analysis (MRA) concepts such as Wavelets, whose potential value in this setting remains underexplored thus far. We show that simple approximations based on empirical feedback and design choices informed by modern hardware and implementation challenges, eventually yield a MRA-based approach for self-attention with an excellent performance profile across most criteria of interest. We undertake an extensive set of experiments and demonstrate that this multi-resolution scheme outperforms most efficient self-attention proposals and is favorable for both short and long sequences. Code is available at https://github.com/mlpen/mra-attention.*
+
+This model was contributed by [novice03](https://huggingface.co/novice03).
+The original code can be found [here](https://github.com/mlpen/mra-attention).
+
+## MraConfig
+
+[[autodoc]] MraConfig
+
+## MraModel
+
+[[autodoc]] MraModel
+ - forward
+
+## MraForMaskedLM
+
+[[autodoc]] MraForMaskedLM
+ - forward
+
+## MraForSequenceClassification
+
+[[autodoc]] MraForSequenceClassification
+ - forward
+
+## MraForMultipleChoice
+
+[[autodoc]] MraForMultipleChoice
+ - forward
+
+## MraForTokenClassification
+
+[[autodoc]] MraForTokenClassification
+ - forward
+
+## MraForQuestionAnswering
+
+[[autodoc]] MraForQuestionAnswering
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mt5.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mt5.md
new file mode 100644
index 0000000000000000000000000000000000000000..7f053bb724a11104cb2924e377380b531b426d58
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mt5.md
@@ -0,0 +1,143 @@
+
+
+# mT5
+
+
+
+## Overview
+
+The mT5 model was presented in [mT5: A massively multilingual pre-trained text-to-text transformer](https://arxiv.org/abs/2010.11934) by Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya
+Siddhant, Aditya Barua, Colin Raffel.
+
+The abstract from the paper is the following:
+
+*The recent "Text-to-Text Transfer Transformer" (T5) leveraged a unified text-to-text format and scale to attain
+state-of-the-art results on a wide variety of English-language NLP tasks. In this paper, we introduce mT5, a
+multilingual variant of T5 that was pre-trained on a new Common Crawl-based dataset covering 101 languages. We detail
+the design and modified training of mT5 and demonstrate its state-of-the-art performance on many multilingual
+benchmarks. We also describe a simple technique to prevent "accidental translation" in the zero-shot setting, where a
+generative model chooses to (partially) translate its prediction into the wrong language. All of the code and model
+checkpoints used in this work are publicly available.*
+
+Note: mT5 was only pre-trained on [mC4](https://huggingface.co/datasets/mc4) excluding any supervised training.
+Therefore, this model has to be fine-tuned before it is usable on a downstream task, unlike the original T5 model.
+Since mT5 was pre-trained unsupervisedly, there's no real advantage to using a task prefix during single-task
+fine-tuning. If you are doing multi-task fine-tuning, you should use a prefix.
+
+Google has released the following variants:
+
+- [google/mt5-small](https://huggingface.co/google/mt5-small)
+
+- [google/mt5-base](https://huggingface.co/google/mt5-base)
+
+- [google/mt5-large](https://huggingface.co/google/mt5-large)
+
+- [google/mt5-xl](https://huggingface.co/google/mt5-xl)
+
+- [google/mt5-xxl](https://huggingface.co/google/mt5-xxl).
+
+This model was contributed by [patrickvonplaten](https://huggingface.co/patrickvonplaten). The original code can be
+found [here](https://github.com/google-research/multilingual-t5).
+
+## Resources
+
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## MT5Config
+
+[[autodoc]] MT5Config
+
+## MT5Tokenizer
+
+[[autodoc]] MT5Tokenizer
+
+See [`T5Tokenizer`] for all details.
+
+
+## MT5TokenizerFast
+
+[[autodoc]] MT5TokenizerFast
+
+See [`T5TokenizerFast`] for all details.
+
+
+
+
+## MT5Model
+
+[[autodoc]] MT5Model
+
+## MT5ForConditionalGeneration
+
+[[autodoc]] MT5ForConditionalGeneration
+
+## MT5EncoderModel
+
+[[autodoc]] MT5EncoderModel
+
+## MT5ForSequenceClassification
+
+[[autodoc]] MT5ForSequenceClassification
+
+## MT5ForTokenClassification
+
+[[autodoc]] MT5ForTokenClassification
+
+## MT5ForQuestionAnswering
+
+[[autodoc]] MT5ForQuestionAnswering
+
+
+
+
+## TFMT5Model
+
+[[autodoc]] TFMT5Model
+
+## TFMT5ForConditionalGeneration
+
+[[autodoc]] TFMT5ForConditionalGeneration
+
+## TFMT5EncoderModel
+
+[[autodoc]] TFMT5EncoderModel
+
+
+
+
+## FlaxMT5Model
+
+[[autodoc]] FlaxMT5Model
+
+## FlaxMT5ForConditionalGeneration
+
+[[autodoc]] FlaxMT5ForConditionalGeneration
+
+## FlaxMT5EncoderModel
+
+[[autodoc]] FlaxMT5EncoderModel
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/musicgen.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/musicgen.md
new file mode 100644
index 0000000000000000000000000000000000000000..7c105e1f39f7ce55e81cc53dbc165f9317a6fab1
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/musicgen.md
@@ -0,0 +1,280 @@
+
+
+# MusicGen
+
+## Overview
+
+The MusicGen model was proposed in the paper [Simple and Controllable Music Generation](https://arxiv.org/abs/2306.05284)
+by Jade Copet, Felix Kreuk, Itai Gat, Tal Remez, David Kant, Gabriel Synnaeve, Yossi Adi and Alexandre Défossez.
+
+MusicGen is a single stage auto-regressive Transformer model capable of generating high-quality music samples conditioned
+on text descriptions or audio prompts. The text descriptions are passed through a frozen text encoder model to obtain a
+sequence of hidden-state representations. MusicGen is then trained to predict discrete audio tokens, or *audio codes*,
+conditioned on these hidden-states. These audio tokens are then decoded using an audio compression model, such as EnCodec,
+to recover the audio waveform.
+
+Through an efficient token interleaving pattern, MusicGen does not require a self-supervised semantic representation of
+the text/audio prompts, thus eliminating the need to cascade multiple models to predict a set of codebooks (e.g.
+hierarchically or upsampling). Instead, it is able to generate all the codebooks in a single forward pass.
+
+The abstract from the paper is the following:
+
+*We tackle the task of conditional music generation. We introduce MusicGen, a single Language Model (LM) that operates
+over several streams of compressed discrete music representation, i.e., tokens. Unlike prior work, MusicGen is comprised
+of a single-stage transformer LM together with efficient token interleaving patterns, which eliminates the need for
+cascading several models, e.g., hierarchically or upsampling. Following this approach, we demonstrate how MusicGen
+can generate high-quality samples, while being conditioned on textual description or melodic features, allowing better
+controls over the generated output. We conduct extensive empirical evaluation, considering both automatic and human
+studies, showing the proposed approach is superior to the evaluated baselines on a standard text-to-music benchmark.
+Through ablation studies, we shed light over the importance of each of the components comprising MusicGen.*
+
+This model was contributed by [sanchit-gandhi](https://huggingface.co/sanchit-gandhi). The original code can be found
+[here](https://github.com/facebookresearch/audiocraft). The pre-trained checkpoints can be found on the
+[Hugging Face Hub](https://huggingface.co/models?sort=downloads&search=facebook%2Fmusicgen-).
+
+## Usage tips
+
+- After downloading the original checkpoints from [here](https://github.com/facebookresearch/audiocraft/blob/main/docs/MUSICGEN.md#importing--exporting-models) , you can convert them using the **conversion script** available at
+`src/transformers/models/musicgen/convert_musicgen_transformers.py` with the following command:
+
+```bash
+python src/transformers/models/musicgen/convert_musicgen_transformers.py \
+ --checkpoint small --pytorch_dump_folder /output/path --safe_serialization
+```
+
+## Generation
+
+MusicGen is compatible with two generation modes: greedy and sampling. In practice, sampling leads to significantly
+better results than greedy, thus we encourage sampling mode to be used where possible. Sampling is enabled by default,
+and can be explicitly specified by setting `do_sample=True` in the call to [`MusicgenForConditionalGeneration.generate`],
+or by overriding the model's generation config (see below).
+
+Generation is limited by the sinusoidal positional embeddings to 30 second inputs. Meaning, MusicGen cannot generate more
+than 30 seconds of audio (1503 tokens), and input audio passed by Audio-Prompted Generation contributes to this limit so,
+given an input of 20 seconds of audio, MusicGen cannot generate more than 10 seconds of additional audio.
+
+Transformers supports both mono (1-channel) and stereo (2-channel) variants of MusicGen. The mono channel versions
+generate a single set of codebooks. The stereo versions generate 2 sets of codebooks, 1 for each channel (left/right),
+and each set of codebooks is decoded independently through the audio compression model. The audio streams for each
+channel are combined to give the final stereo output.
+
+### Unconditional Generation
+
+The inputs for unconditional (or 'null') generation can be obtained through the method
+[`MusicgenForConditionalGeneration.get_unconditional_inputs`]:
+
+```python
+>>> from transformers import MusicgenForConditionalGeneration
+
+>>> model = MusicgenForConditionalGeneration.from_pretrained("facebook/musicgen-small")
+>>> unconditional_inputs = model.get_unconditional_inputs(num_samples=1)
+
+>>> audio_values = model.generate(**unconditional_inputs, do_sample=True, max_new_tokens=256)
+```
+
+The audio outputs are a three-dimensional Torch tensor of shape `(batch_size, num_channels, sequence_length)`. To listen
+to the generated audio samples, you can either play them in an ipynb notebook:
+
+```python
+from IPython.display import Audio
+
+sampling_rate = model.config.audio_encoder.sampling_rate
+Audio(audio_values[0].numpy(), rate=sampling_rate)
+```
+
+Or save them as a `.wav` file using a third-party library, e.g. `scipy`:
+
+```python
+>>> import scipy
+
+>>> sampling_rate = model.config.audio_encoder.sampling_rate
+>>> scipy.io.wavfile.write("musicgen_out.wav", rate=sampling_rate, data=audio_values[0, 0].numpy())
+```
+
+### Text-Conditional Generation
+
+The model can generate an audio sample conditioned on a text prompt through use of the [`MusicgenProcessor`] to pre-process
+the inputs:
+
+```python
+>>> from transformers import AutoProcessor, MusicgenForConditionalGeneration
+
+>>> processor = AutoProcessor.from_pretrained("facebook/musicgen-small")
+>>> model = MusicgenForConditionalGeneration.from_pretrained("facebook/musicgen-small")
+
+>>> inputs = processor(
+... text=["80s pop track with bassy drums and synth", "90s rock song with loud guitars and heavy drums"],
+... padding=True,
+... return_tensors="pt",
+... )
+>>> audio_values = model.generate(**inputs, do_sample=True, guidance_scale=3, max_new_tokens=256)
+```
+
+The `guidance_scale` is used in classifier free guidance (CFG), setting the weighting between the conditional logits
+(which are predicted from the text prompts) and the unconditional logits (which are predicted from an unconditional or
+'null' prompt). Higher guidance scale encourages the model to generate samples that are more closely linked to the input
+prompt, usually at the expense of poorer audio quality. CFG is enabled by setting `guidance_scale > 1`. For best results,
+use `guidance_scale=3` (default).
+
+### Audio-Prompted Generation
+
+The same [`MusicgenProcessor`] can be used to pre-process an audio prompt that is used for audio continuation. In the
+following example, we load an audio file using the 🤗 Datasets library, which can be pip installed through the command
+below:
+
+```bash
+pip install --upgrade pip
+pip install datasets[audio]
+```
+
+```python
+>>> from transformers import AutoProcessor, MusicgenForConditionalGeneration
+>>> from datasets import load_dataset
+
+>>> processor = AutoProcessor.from_pretrained("facebook/musicgen-small")
+>>> model = MusicgenForConditionalGeneration.from_pretrained("facebook/musicgen-small")
+
+>>> dataset = load_dataset("sanchit-gandhi/gtzan", split="train", streaming=True)
+>>> sample = next(iter(dataset))["audio"]
+
+>>> # take the first half of the audio sample
+>>> sample["array"] = sample["array"][: len(sample["array"]) // 2]
+
+>>> inputs = processor(
+... audio=sample["array"],
+... sampling_rate=sample["sampling_rate"],
+... text=["80s blues track with groovy saxophone"],
+... padding=True,
+... return_tensors="pt",
+... )
+>>> audio_values = model.generate(**inputs, do_sample=True, guidance_scale=3, max_new_tokens=256)
+```
+
+For batched audio-prompted generation, the generated `audio_values` can be post-processed to remove padding by using the
+[`MusicgenProcessor`] class:
+
+```python
+>>> from transformers import AutoProcessor, MusicgenForConditionalGeneration
+>>> from datasets import load_dataset
+
+>>> processor = AutoProcessor.from_pretrained("facebook/musicgen-small")
+>>> model = MusicgenForConditionalGeneration.from_pretrained("facebook/musicgen-small")
+
+>>> dataset = load_dataset("sanchit-gandhi/gtzan", split="train", streaming=True)
+>>> sample = next(iter(dataset))["audio"]
+
+>>> # take the first quarter of the audio sample
+>>> sample_1 = sample["array"][: len(sample["array"]) // 4]
+
+>>> # take the first half of the audio sample
+>>> sample_2 = sample["array"][: len(sample["array"]) // 2]
+
+>>> inputs = processor(
+... audio=[sample_1, sample_2],
+... sampling_rate=sample["sampling_rate"],
+... text=["80s blues track with groovy saxophone", "90s rock song with loud guitars and heavy drums"],
+... padding=True,
+... return_tensors="pt",
+... )
+>>> audio_values = model.generate(**inputs, do_sample=True, guidance_scale=3, max_new_tokens=256)
+
+>>> # post-process to remove padding from the batched audio
+>>> audio_values = processor.batch_decode(audio_values, padding_mask=inputs.padding_mask)
+```
+
+### Generation Configuration
+
+The default parameters that control the generation process, such as sampling, guidance scale and number of generated
+tokens, can be found in the model's generation config, and updated as desired:
+
+```python
+>>> from transformers import MusicgenForConditionalGeneration
+
+>>> model = MusicgenForConditionalGeneration.from_pretrained("facebook/musicgen-small")
+
+>>> # inspect the default generation config
+>>> model.generation_config
+
+>>> # increase the guidance scale to 4.0
+>>> model.generation_config.guidance_scale = 4.0
+
+>>> # decrease the max length to 256 tokens
+>>> model.generation_config.max_length = 256
+```
+
+Note that any arguments passed to the generate method will **supersede** those in the generation config, so setting
+`do_sample=False` in the call to generate will supersede the setting of `model.generation_config.do_sample` in the
+generation config.
+
+## Model Structure
+
+The MusicGen model can be de-composed into three distinct stages:
+1. Text encoder: maps the text inputs to a sequence of hidden-state representations. The pre-trained MusicGen models use a frozen text encoder from either T5 or Flan-T5
+2. MusicGen decoder: a language model (LM) that auto-regressively generates audio tokens (or codes) conditional on the encoder hidden-state representations
+3. Audio encoder/decoder: used to encode an audio prompt to use as prompt tokens, and recover the audio waveform from the audio tokens predicted by the decoder
+
+Thus, the MusicGen model can either be used as a standalone decoder model, corresponding to the class [`MusicgenForCausalLM`],
+or as a composite model that includes the text encoder and audio encoder/decoder, corresponding to the class
+[`MusicgenForConditionalGeneration`]. If only the decoder needs to be loaded from the pre-trained checkpoint, it can be loaded by first
+specifying the correct config, or be accessed through the `.decoder` attribute of the composite model:
+
+```python
+>>> from transformers import AutoConfig, MusicgenForCausalLM, MusicgenForConditionalGeneration
+
+>>> # Option 1: get decoder config and pass to `.from_pretrained`
+>>> decoder_config = AutoConfig.from_pretrained("facebook/musicgen-small").decoder
+>>> decoder = MusicgenForCausalLM.from_pretrained("facebook/musicgen-small", **decoder_config)
+
+>>> # Option 2: load the entire composite model, but only return the decoder
+>>> decoder = MusicgenForConditionalGeneration.from_pretrained("facebook/musicgen-small").decoder
+```
+
+Since the text encoder and audio encoder/decoder models are frozen during training, the MusicGen decoder [`MusicgenForCausalLM`]
+can be trained standalone on a dataset of encoder hidden-states and audio codes. For inference, the trained decoder can
+be combined with the frozen text encoder and audio encoder/decoders to recover the composite [`MusicgenForConditionalGeneration`]
+model.
+
+Tips:
+* MusicGen is trained on the 32kHz checkpoint of Encodec. You should ensure you use a compatible version of the Encodec model.
+* Sampling mode tends to deliver better results than greedy - you can toggle sampling with the variable `do_sample` in the call to [`MusicgenForConditionalGeneration.generate`]
+
+## MusicgenDecoderConfig
+
+[[autodoc]] MusicgenDecoderConfig
+
+## MusicgenConfig
+
+[[autodoc]] MusicgenConfig
+
+## MusicgenProcessor
+
+[[autodoc]] MusicgenProcessor
+
+## MusicgenModel
+
+[[autodoc]] MusicgenModel
+ - forward
+
+## MusicgenForCausalLM
+
+[[autodoc]] MusicgenForCausalLM
+ - forward
+
+## MusicgenForConditionalGeneration
+
+[[autodoc]] MusicgenForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/musicgen_melody.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/musicgen_melody.md
new file mode 100644
index 0000000000000000000000000000000000000000..4d92d861f0bb5f0b80115961c84f9f03f5a5ebcc
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/musicgen_melody.md
@@ -0,0 +1,288 @@
+
+
+# MusicGen Melody
+
+## Overview
+
+The MusicGen Melody model was proposed in [Simple and Controllable Music Generation](https://arxiv.org/abs/2306.05284) by Jade Copet, Felix Kreuk, Itai Gat, Tal Remez, David Kant, Gabriel Synnaeve, Yossi Adi and Alexandre Défossez.
+
+MusicGen Melody is a single stage auto-regressive Transformer model capable of generating high-quality music samples conditioned on text descriptions or audio prompts. The text descriptions are passed through a frozen text encoder model to obtain a sequence of hidden-state representations. MusicGen is then trained to predict discrete audio tokens, or *audio codes*, conditioned on these hidden-states. These audio tokens are then decoded using an audio compression model, such as EnCodec, to recover the audio waveform.
+
+Through an efficient token interleaving pattern, MusicGen does not require a self-supervised semantic representation of the text/audio prompts, thus eliminating the need to cascade multiple models to predict a set of codebooks (e.g. hierarchically or upsampling). Instead, it is able to generate all the codebooks in a single forward pass.
+
+The abstract from the paper is the following:
+
+*We tackle the task of conditional music generation. We introduce MusicGen, a single Language Model (LM) that operates over several streams of compressed discrete music representation, i.e., tokens. Unlike prior work, MusicGen is comprised of a single-stage transformer LM together with efficient token interleaving patterns, which eliminates the need for cascading several models, e.g., hierarchically or upsampling. Following this approach, we demonstrate how MusicGen can generate high-quality samples, while being conditioned on textual description or melodic features, allowing better controls over the generated output. We conduct extensive empirical evaluation, considering both automatic and human studies, showing the proposed approach is superior to the evaluated baselines on a standard text-to-music benchmark. Through ablation studies, we shed light over the importance of each of the components comprising MusicGen.*
+
+
+This model was contributed by [ylacombe](https://huggingface.co/ylacombe). The original code can be found [here](https://github.com/facebookresearch/audiocraft). The pre-trained checkpoints can be found on the [Hugging Face Hub](https://huggingface.co/models?sort=downloads&search=facebook%2Fmusicgen).
+
+
+## Difference with [MusicGen](https://huggingface.co/docs/transformers/main/en/model_doc/musicgen)
+
+There are two key differences with MusicGen:
+1. The audio prompt is used here as a conditional signal for the generated audio sample, whereas it's used for audio continuation in [MusicGen](https://huggingface.co/docs/transformers/main/en/model_doc/musicgen).
+2. Conditional text and audio signals are concatenated to the decoder's hidden states instead of being used as a cross-attention signal, as in MusicGen.
+
+## Generation
+
+MusicGen Melody is compatible with two generation modes: greedy and sampling. In practice, sampling leads to significantly better results than greedy, thus we encourage sampling mode to be used where possible. Sampling is enabled by default, and can be explicitly specified by setting `do_sample=True` in the call to [`MusicgenMelodyForConditionalGeneration.generate`], or by overriding the model's generation config (see below).
+
+Transformers supports both mono (1-channel) and stereo (2-channel) variants of MusicGen Melody. The mono channel versions generate a single set of codebooks. The stereo versions generate 2 sets of codebooks, 1 for each channel (left/right), and each set of codebooks is decoded independently through the audio compression model. The audio streams for each channel are combined to give the final stereo output.
+
+
+#### Audio Conditional Generation
+
+The model can generate an audio sample conditioned on a text and an audio prompt through use of the [`MusicgenMelodyProcessor`] to pre-process the inputs.
+
+In the following examples, we load an audio file using the 🤗 Datasets library, which can be pip installed through the command below:
+
+```
+pip install --upgrade pip
+pip install datasets[audio]
+```
+
+The audio file we are about to use is loaded as follows:
+```python
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("sanchit-gandhi/gtzan", split="train", streaming=True)
+>>> sample = next(iter(dataset))["audio"]
+```
+
+The audio prompt should ideally be free of the low-frequency signals usually produced by instruments such as drums and bass. The [Demucs](https://github.com/adefossez/demucs/tree/main) model can be used to separate vocals and other signals from the drums and bass components.
+
+If you wish to use Demucs, you first need to follow the installation steps [here](https://github.com/adefossez/demucs/tree/main?tab=readme-ov-file#for-musicians) before using the following snippet:
+
+```python
+from demucs import pretrained
+from demucs.apply import apply_model
+from demucs.audio import convert_audio
+import torch
+
+
+wav = torch.tensor(sample["array"]).to(torch.float32)
+
+demucs = pretrained.get_model('htdemucs')
+
+wav = convert_audio(wav[None], sample["sampling_rate"], demucs.samplerate, demucs.audio_channels)
+wav = apply_model(demucs, wav[None])
+```
+
+You can then use the following snippet to generate music:
+
+```python
+>>> from transformers import AutoProcessor, MusicgenMelodyForConditionalGeneration
+
+>>> processor = AutoProcessor.from_pretrained("facebook/musicgen-melody")
+>>> model = MusicgenMelodyForConditionalGeneration.from_pretrained("facebook/musicgen-melody")
+
+>>> inputs = processor(
+... audio=wav,
+... sampling_rate=demucs.samplerate,
+... text=["80s blues track with groovy saxophone"],
+... padding=True,
+... return_tensors="pt",
+... )
+>>> audio_values = model.generate(**inputs, do_sample=True, guidance_scale=3, max_new_tokens=256)
+```
+
+You can also pass the audio signal directly without using Demucs, although the quality of the generation will probably be degraded:
+
+```python
+>>> from transformers import AutoProcessor, MusicgenMelodyForConditionalGeneration
+
+>>> processor = AutoProcessor.from_pretrained("facebook/musicgen-melody")
+>>> model = MusicgenMelodyForConditionalGeneration.from_pretrained("facebook/musicgen-melody")
+
+>>> inputs = processor(
+... audio=sample["array"],
+... sampling_rate=sample["sampling_rate"],
+... text=["80s blues track with groovy saxophone"],
+... padding=True,
+... return_tensors="pt",
+... )
+>>> audio_values = model.generate(**inputs, do_sample=True, guidance_scale=3, max_new_tokens=256)
+```
+
+The audio outputs are a three-dimensional Torch tensor of shape `(batch_size, num_channels, sequence_length)`. To listen to the generated audio samples, you can either play them in an ipynb notebook:
+
+```python
+from IPython.display import Audio
+
+sampling_rate = model.config.audio_encoder.sampling_rate
+Audio(audio_values[0].numpy(), rate=sampling_rate)
+```
+
+Or save them as a `.wav` file using a third-party library, e.g. `soundfile`:
+
+```python
+>>> import soundfile as sf
+
+>>> sampling_rate = model.config.audio_encoder.sampling_rate
+>>> sf.write("musicgen_out.wav", audio_values[0].T.numpy(), sampling_rate)
+```
+
+
+### Text-only Conditional Generation
+
+The same [`MusicgenMelodyProcessor`] can be used to pre-process a text-only prompt.
+
+```python
+>>> from transformers import AutoProcessor, MusicgenMelodyForConditionalGeneration
+
+>>> processor = AutoProcessor.from_pretrained("facebook/musicgen-melody")
+>>> model = MusicgenMelodyForConditionalGeneration.from_pretrained("facebook/musicgen-melody")
+
+>>> inputs = processor(
+... text=["80s pop track with bassy drums and synth", "90s rock song with loud guitars and heavy drums"],
+... padding=True,
+... return_tensors="pt",
+... )
+>>> audio_values = model.generate(**inputs, do_sample=True, guidance_scale=3, max_new_tokens=256)
+```
+
+The `guidance_scale` is used in classifier free guidance (CFG), setting the weighting between the conditional logits (which are predicted from the text prompts) and the unconditional logits (which are predicted from an unconditional or 'null' prompt). Higher guidance scale encourages the model to generate samples that are more closely linked to the input prompt, usually at the expense of poorer audio quality. CFG is enabled by setting `guidance_scale > 1`. For best results, use `guidance_scale=3` (default).
+
+
+You can also generate in batch:
+
+```python
+>>> from transformers import AutoProcessor, MusicgenMelodyForConditionalGeneration
+>>> from datasets import load_dataset
+
+>>> processor = AutoProcessor.from_pretrained("facebook/musicgen-melody")
+>>> model = MusicgenMelodyForConditionalGeneration.from_pretrained("facebook/musicgen-melody")
+
+>>> # take the first quarter of the audio sample
+>>> sample_1 = sample["array"][: len(sample["array"]) // 4]
+
+>>> # take the first half of the audio sample
+>>> sample_2 = sample["array"][: len(sample["array"]) // 2]
+
+>>> inputs = processor(
+... audio=[sample_1, sample_2],
+... sampling_rate=sample["sampling_rate"],
+... text=["80s blues track with groovy saxophone", "90s rock song with loud guitars and heavy drums"],
+... padding=True,
+... return_tensors="pt",
+... )
+>>> audio_values = model.generate(**inputs, do_sample=True, guidance_scale=3, max_new_tokens=256)
+```
+
+### Unconditional Generation
+
+The inputs for unconditional (or 'null') generation can be obtained through the method [`MusicgenMelodyProcessor.get_unconditional_inputs`]:
+
+```python
+>>> from transformers import MusicgenMelodyForConditionalGeneration, MusicgenMelodyProcessor
+
+>>> model = MusicgenMelodyForConditionalGeneration.from_pretrained("facebook/musicgen-melody")
+>>> unconditional_inputs = MusicgenMelodyProcessor.from_pretrained("facebook/musicgen-melody").get_unconditional_inputs(num_samples=1)
+
+>>> audio_values = model.generate(**unconditional_inputs, do_sample=True, max_new_tokens=256)
+```
+
+### Generation Configuration
+
+The default parameters that control the generation process, such as sampling, guidance scale and number of generated tokens, can be found in the model's generation config, and updated as desired:
+
+```python
+>>> from transformers import MusicgenMelodyForConditionalGeneration
+
+>>> model = MusicgenMelodyForConditionalGeneration.from_pretrained("facebook/musicgen-melody")
+
+>>> # inspect the default generation config
+>>> model.generation_config
+
+>>> # increase the guidance scale to 4.0
+>>> model.generation_config.guidance_scale = 4.0
+
+>>> # decrease the max length to 256 tokens
+>>> model.generation_config.max_length = 256
+```
+
+Note that any arguments passed to the generate method will **supersede** those in the generation config, so setting `do_sample=False` in the call to generate will supersede the setting of `model.generation_config.do_sample` in the generation config.
+
+## Model Structure
+
+The MusicGen model can be de-composed into three distinct stages:
+1. Text encoder: maps the text inputs to a sequence of hidden-state representations. The pre-trained MusicGen models use a frozen text encoder from either T5 or Flan-T5.
+2. MusicGen Melody decoder: a language model (LM) that auto-regressively generates audio tokens (or codes) conditional on the encoder hidden-state representations
+3. Audio decoder: used to recover the audio waveform from the audio tokens predicted by the decoder.
+
+Thus, the MusicGen model can either be used as a standalone decoder model, corresponding to the class [`MusicgenMelodyForCausalLM`], or as a composite model that includes the text encoder and audio encoder, corresponding to the class [`MusicgenMelodyForConditionalGeneration`]. If only the decoder needs to be loaded from the pre-trained checkpoint, it can be loaded by first specifying the correct config, or be accessed through the `.decoder` attribute of the composite model:
+
+```python
+>>> from transformers import AutoConfig, MusicgenMelodyForCausalLM, MusicgenMelodyForConditionalGeneration
+
+>>> # Option 1: get decoder config and pass to `.from_pretrained`
+>>> decoder_config = AutoConfig.from_pretrained("facebook/musicgen-melody").decoder
+>>> decoder = MusicgenMelodyForCausalLM.from_pretrained("facebook/musicgen-melody", **decoder_config.to_dict())
+
+>>> # Option 2: load the entire composite model, but only return the decoder
+>>> decoder = MusicgenMelodyForConditionalGeneration.from_pretrained("facebook/musicgen-melody").decoder
+```
+
+Since the text encoder and audio encoder models are frozen during training, the MusicGen decoder [`MusicgenMelodyForCausalLM`] can be trained standalone on a dataset of encoder hidden-states and audio codes. For inference, the trained decoder can be combined with the frozen text encoder and audio encoder to recover the composite [`MusicgenMelodyForConditionalGeneration`] model.
+
+## Checkpoint Conversion
+
+- After downloading the original checkpoints from [here](https://github.com/facebookresearch/audiocraft/blob/main/docs/MUSICGEN.md#importing--exporting-models), you can convert them using the **conversion script** available at `src/transformers/models/musicgen_melody/convert_musicgen_melody_transformers.py` with the following command:
+
+```bash
+python src/transformers/models/musicgen_melody/convert_musicgen_melody_transformers.py \
+ --checkpoint="facebook/musicgen-melody" --pytorch_dump_folder /output/path
+```
+
+Tips:
+* MusicGen is trained on the 32kHz checkpoint of Encodec. You should ensure you use a compatible version of the Encodec model.
+* Sampling mode tends to deliver better results than greedy - you can toggle sampling with the variable `do_sample` in the call to [`MusicgenMelodyForConditionalGeneration.generate`]
+
+
+## MusicgenMelodyDecoderConfig
+
+[[autodoc]] MusicgenMelodyDecoderConfig
+
+## MusicgenMelodyProcessor
+
+[[autodoc]] MusicgenMelodyProcessor
+ - get_unconditional_inputs
+
+## MusicgenMelodyFeatureExtractor
+
+[[autodoc]] MusicgenMelodyFeatureExtractor
+ - _extract_stem_indices
+
+## MusicgenMelodyConfig
+
+[[autodoc]] MusicgenMelodyConfig
+
+## MusicgenMelodyModel
+
+[[autodoc]] MusicgenMelodyModel
+ - forward
+
+## MusicgenMelodyForCausalLM
+
+[[autodoc]] MusicgenMelodyForCausalLM
+ - forward
+
+## MusicgenMelodyForConditionalGeneration
+
+[[autodoc]] MusicgenMelodyForConditionalGeneration
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mvp.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mvp.md
new file mode 100644
index 0000000000000000000000000000000000000000..0d98e04cf091ee3837a83d6ebd9b69b8a7a6a8fe
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mvp.md
@@ -0,0 +1,153 @@
+
+
+# MVP
+
+## Overview
+
+The MVP model was proposed in [MVP: Multi-task Supervised Pre-training for Natural Language Generation](https://arxiv.org/abs/2206.12131) by Tianyi Tang, Junyi Li, Wayne Xin Zhao and Ji-Rong Wen.
+
+
+According to the abstract,
+
+- MVP follows a standard Transformer encoder-decoder architecture.
+- MVP is supervised pre-trained using labeled datasets.
+- MVP also has task-specific soft prompts to stimulate the model's capacity in performing a certain task.
+- MVP is specially designed for natural language generation and can be adapted to a wide range of generation tasks, including but not limited to summarization, data-to-text generation, open-ended dialogue system, story generation, question answering, question generation, task-oriented dialogue system, commonsense generation, paraphrase generation, text style transfer, and text simplification. Our model can also be adapted to natural language understanding tasks such as sequence classification and (extractive) question answering.
+
+This model was contributed by [Tianyi Tang](https://huggingface.co/StevenTang). The detailed information and instructions can be found [here](https://github.com/RUCAIBox/MVP).
+
+## Usage tips
+
+- We have released a series of models [here](https://huggingface.co/models?filter=mvp), including MVP, MVP with task-specific prompts, and multi-task pre-trained variants.
+- If you want to use a model without prompts (standard Transformer), you can load it through `MvpForConditionalGeneration.from_pretrained('RUCAIBox/mvp')`.
+- If you want to use a model with task-specific prompts, such as summarization, you can load it through `MvpForConditionalGeneration.from_pretrained('RUCAIBox/mvp-summarization')`.
+- Our model supports lightweight prompt tuning following [Prefix-tuning](https://arxiv.org/abs/2101.00190) with method `set_lightweight_tuning()`.
+
+## Usage examples
+
+For summarization, it is an example to use MVP and MVP with summarization-specific prompts.
+
+```python
+>>> from transformers import MvpTokenizer, MvpForConditionalGeneration
+
+>>> tokenizer = MvpTokenizer.from_pretrained("RUCAIBox/mvp")
+>>> model = MvpForConditionalGeneration.from_pretrained("RUCAIBox/mvp")
+>>> model_with_prompt = MvpForConditionalGeneration.from_pretrained("RUCAIBox/mvp-summarization")
+
+>>> inputs = tokenizer(
+... "Summarize: You may want to stick it to your boss and leave your job, but don't do it if these are your reasons.",
+... return_tensors="pt",
+... )
+>>> generated_ids = model.generate(**inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+["Why You Shouldn't Quit Your Job"]
+
+>>> generated_ids = model_with_prompt.generate(**inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+["Don't do it if these are your reasons"]
+```
+
+For data-to-text generation, it is an example to use MVP and multi-task pre-trained variants.
+```python
+>>> from transformers import MvpTokenizerFast, MvpForConditionalGeneration
+
+>>> tokenizer = MvpTokenizerFast.from_pretrained("RUCAIBox/mvp")
+>>> model = MvpForConditionalGeneration.from_pretrained("RUCAIBox/mvp")
+>>> model_with_mtl = MvpForConditionalGeneration.from_pretrained("RUCAIBox/mtl-data-to-text")
+
+>>> inputs = tokenizer(
+... "Describe the following data: Iron Man | instance of | Superhero [SEP] Stan Lee | creator | Iron Man",
+... return_tensors="pt",
+... )
+>>> generated_ids = model.generate(**inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+['Stan Lee created the character of Iron Man, a fictional superhero appearing in American comic']
+
+>>> generated_ids = model_with_mtl.generate(**inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+['Iron Man is a fictional superhero appearing in American comic books published by Marvel Comics.']
+```
+
+For lightweight tuning, *i.e.*, fixing the model and only tuning prompts, you can load MVP with randomly initialized prompts or with task-specific prompts. Our code also supports Prefix-tuning with BART following the [original paper](https://arxiv.org/abs/2101.00190).
+
+```python
+>>> from transformers import MvpForConditionalGeneration
+
+>>> model = MvpForConditionalGeneration.from_pretrained("RUCAIBox/mvp", use_prompt=True)
+>>> # the number of trainable parameters (full tuning)
+>>> sum(p.numel() for p in model.parameters() if p.requires_grad)
+468116832
+
+>>> # lightweight tuning with randomly initialized prompts
+>>> model.set_lightweight_tuning()
+>>> # the number of trainable parameters (lightweight tuning)
+>>> sum(p.numel() for p in model.parameters() if p.requires_grad)
+61823328
+
+>>> # lightweight tuning with task-specific prompts
+>>> model = MvpForConditionalGeneration.from_pretrained("RUCAIBox/mtl-data-to-text")
+>>> model.set_lightweight_tuning()
+>>> # original lightweight Prefix-tuning
+>>> model = MvpForConditionalGeneration.from_pretrained("facebook/bart-large", use_prompt=True)
+>>> model.set_lightweight_tuning()
+```
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## MvpConfig
+
+[[autodoc]] MvpConfig
+
+## MvpTokenizer
+
+[[autodoc]] MvpTokenizer
+
+## MvpTokenizerFast
+
+[[autodoc]] MvpTokenizerFast
+
+## MvpModel
+
+[[autodoc]] MvpModel
+ - forward
+
+## MvpForConditionalGeneration
+
+[[autodoc]] MvpForConditionalGeneration
+ - forward
+
+## MvpForSequenceClassification
+
+[[autodoc]] MvpForSequenceClassification
+ - forward
+
+## MvpForQuestionAnswering
+
+[[autodoc]] MvpForQuestionAnswering
+ - forward
+
+## MvpForCausalLM
+
+[[autodoc]] MvpForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/myt5.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/myt5.md
new file mode 100644
index 0000000000000000000000000000000000000000..c8b46f43512b6edcee329b1d4537e26802cebb2a
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/myt5.md
@@ -0,0 +1,46 @@
+
+
+# myt5
+
+## Overview
+
+The myt5 model was proposed in [MYTE: Morphology-Driven Byte Encoding for Better and Fairer Multilingual Language Modeling](https://arxiv.org/pdf/2403.10691.pdf) by Tomasz Limisiewicz, Terra Blevins, Hila Gonen, Orevaoghene Ahia, and Luke Zettlemoyer.
+MyT5 (**My**te **T5**) is a multilingual language model based on T5 architecture.
+The model uses a **m**orphologically-driven **byte** (**MYTE**) representation described in our paper.
+**MYTE** uses codepoints corresponding to morphemes in contrast to characters used in UTF-8 encoding.
+As a pre-requisite, we used unsupervised morphological segmentation ([Morfessor](https://aclanthology.org/E14-2006.pdf)) to obtain morpheme inventories for 99 languages.
+However, the morphological segmentation step is not needed when using the pre-defined morpheme inventory from the hub (see: [Tomli/myt5-base](https://huggingface.co/Tomlim/myt5-base)).
+
+The abstract from the paper is the following:
+
+*A major consideration in multilingual language modeling is how to best represent languages with diverse vocabularies and scripts. Although contemporary text encoding methods cover most of the world’s writing systems, they exhibit bias towards the high-resource languages of the Global West. As a result, texts of underrepresented languages tend to be segmented into long sequences of linguistically meaningless units. To address the disparities, we introduce a new paradigm that encodes the same information with segments of consistent size across diverse languages. Our encoding convention (MYTE) is based on morphemes, as their inventories are more balanced across languages than characters, which are used in previous methods. We show that MYTE produces shorter encodings for all 99 analyzed languages, with the most notable improvements for non-European languages and non-Latin scripts. This, in turn, improves multilingual LM performance and diminishes the perplexity gap throughout diverse languages.*
+
+This model was contributed by [Tomasz Limisiewicz](https://huggingface.co/Tomlim).
+The original code can be found [here](https://github.com/tomlimi/MYTE).
+
+## MyT5Tokenizer
+
+[[autodoc]] MyT5Tokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## MyT5Tokenizer
+
+[[autodoc]] MyT5Tokenizer
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nat.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nat.md
new file mode 100644
index 0000000000000000000000000000000000000000..02c2e466cc4a7bba38b7fae86da16dbcfb4da457
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nat.md
@@ -0,0 +1,95 @@
+
+
+# Neighborhood Attention Transformer
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+NAT was proposed in [Neighborhood Attention Transformer](https://arxiv.org/abs/2204.07143)
+by Ali Hassani, Steven Walton, Jiachen Li, Shen Li, and Humphrey Shi.
+
+It is a hierarchical vision transformer based on Neighborhood Attention, a sliding-window self attention pattern.
+
+The abstract from the paper is the following:
+
+*We present Neighborhood Attention (NA), the first efficient and scalable sliding-window attention mechanism for vision.
+NA is a pixel-wise operation, localizing self attention (SA) to the nearest neighboring pixels, and therefore enjoys a
+linear time and space complexity compared to the quadratic complexity of SA. The sliding-window pattern allows NA's
+receptive field to grow without needing extra pixel shifts, and preserves translational equivariance, unlike
+Swin Transformer's Window Self Attention (WSA). We develop NATTEN (Neighborhood Attention Extension), a Python package
+with efficient C++ and CUDA kernels, which allows NA to run up to 40% faster than Swin's WSA while using up to 25% less
+memory. We further present Neighborhood Attention Transformer (NAT), a new hierarchical transformer design based on NA
+that boosts image classification and downstream vision performance. Experimental results on NAT are competitive;
+NAT-Tiny reaches 83.2% top-1 accuracy on ImageNet, 51.4% mAP on MS-COCO and 48.4% mIoU on ADE20K, which is 1.9%
+ImageNet accuracy, 1.0% COCO mAP, and 2.6% ADE20K mIoU improvement over a Swin model with similar size. *
+
+
+
+ Neighborhood Attention compared to other attention patterns.
+Taken from the original paper.
+
+This model was contributed by [Ali Hassani](https://huggingface.co/alihassanijr).
+The original code can be found [here](https://github.com/SHI-Labs/Neighborhood-Attention-Transformer).
+
+## Usage tips
+
+- One can use the [`AutoImageProcessor`] API to prepare images for the model.
+- NAT can be used as a *backbone*. When `output_hidden_states = True`,
+it will output both `hidden_states` and `reshaped_hidden_states`.
+The `reshaped_hidden_states` have a shape of `(batch, num_channels, height, width)` rather than
+`(batch_size, height, width, num_channels)`.
+
+Notes:
+- NAT depends on [NATTEN](https://github.com/SHI-Labs/NATTEN/)'s implementation of Neighborhood Attention.
+You can install it with pre-built wheels for Linux by referring to [shi-labs.com/natten](https://shi-labs.com/natten),
+or build on your system by running `pip install natten`.
+Note that the latter will likely take time to compile. NATTEN does not support Windows devices yet.
+- Patch size of 4 is only supported at the moment.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with NAT.
+
+
+
+- [`NatForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## NatConfig
+
+[[autodoc]] NatConfig
+
+## NatModel
+
+[[autodoc]] NatModel
+ - forward
+
+## NatForImageClassification
+
+[[autodoc]] NatForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nemotron.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nemotron.md
new file mode 100644
index 0000000000000000000000000000000000000000..1979847c43cfc95c005888f97d0df5d08c28950e
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nemotron.md
@@ -0,0 +1,148 @@
+
+
+# Nemotron
+
+## Nemotron
+
+### License
+
+The use of this model is governed by the [NVIDIA AI Foundation Models Community License Agreement](https://developer.nvidia.com/downloads/nv-ai-foundation-models-license).
+
+### Description
+
+Nemotron-4 is a family of enterprise ready generative text models compatible with [NVIDIA NeMo Framework](https://www.nvidia.com/en-us/ai-data-science/generative-ai/nemo-framework/).
+
+NVIDIA NeMo is an end-to-end, cloud-native platform to build, customize, and deploy generative AI models anywhere. It includes training and inferencing frameworks, guardrailing toolkits, data curation tools, and pretrained models, offering enterprises an easy, cost-effective, and fast way to adopt generative AI. To get access to NeMo Framework, please sign up at [this link](https://developer.nvidia.com/nemo-framework/join).
+
+### References
+
+[Announcement Blog](https://developer.nvidia.com/blog/nvidia-ai-foundation-models-build-custom-enterprise-chatbots-and-co-pilots-with-production-ready-llms/)
+
+### Model Architecture
+
+**Architecture Type:** Transformer
+
+**Network Architecture:** Transformer Decoder (auto-regressive language model).
+
+## Minitron
+
+### Minitron 4B Base
+
+Minitron is a family of small language models (SLMs) obtained by pruning NVIDIA's [Nemotron-4 15B](https://arxiv.org/abs/2402.16819) model. We prune model embedding size, attention heads, and MLP intermediate dimension, following which, we perform continued training with distillation to arrive at the final models.
+
+Deriving the Minitron 8B and 4B models from the base 15B model using our approach requires up to **40x fewer training tokens** per model compared to training from scratch; this results in **compute cost savings of 1.8x** for training the full model family (15B, 8B, and 4B). Minitron models exhibit up to a 16% improvement in MMLU scores compared to training from scratch, perform comparably to other community models such as Mistral 7B, Gemma 7B and Llama-3 8B, and outperform state-of-the-art compression techniques from the literature. Please refer to our [arXiv paper](https://arxiv.org/abs/2407.14679) for more details.
+
+Minitron models are for research and development only.
+
+### HuggingFace Quickstart
+
+The following code provides an example of how to load the Minitron-4B model and use it to perform text generation.
+
+```python
+import torch
+from transformers import AutoTokenizer, AutoModelForCausalLM
+
+# Load the tokenizer and model
+model_path = 'nvidia/Minitron-4B-Base'
+tokenizer = AutoTokenizer.from_pretrained(model_path)
+
+device = 'cuda'
+dtype = torch.bfloat16
+model = AutoModelForCausalLM.from_pretrained(model_path, torch_dtype=dtype, device_map=device)
+
+# Prepare the input text
+prompt = 'Complete the paragraph: our solar system is'
+inputs = tokenizer.encode(prompt, return_tensors='pt').to(model.device)
+
+# Generate the output
+outputs = model.generate(inputs, max_length=20)
+
+# Decode and print the output
+output_text = tokenizer.decode(outputs[0])
+print(output_text)
+```
+
+### License
+
+Minitron is released under the [NVIDIA Open Model License Agreement](https://developer.download.nvidia.com/licenses/nvidia-open-model-license-agreement-june-2024.pdf).
+
+### Evaluation Results
+
+*5-shot performance.* Language Understanding evaluated using [Massive Multitask Language Understanding](https://arxiv.org/abs/2009.03300):
+
+| Average |
+| :---- |
+| 58.6 |
+
+*Zero-shot performance.* Evaluated using select datasets from the [LM Evaluation Harness](https://github.com/EleutherAI/lm-evaluation-harness) with additions:
+
+| HellaSwag | Winogrande | GSM8K| ARC-C | XLSum |
+| :------------- | :------------- | :------------- | :------------- | :------------- |
+| 75.0 | 74.0 | 24.1 | 50.9 | 29.5
+
+
+*Code generation performance*. Evaluated using [HumanEval](https://github.com/openai/human-eval):
+
+| p@1, 0-Shot |
+| :------------- |
+| 23.3 |
+
+Please refer to our [paper](https://arxiv.org/abs/2407.14679) for the full set of results.
+
+### Citation
+
+If you find our work helpful, please consider citing our paper:
+```
+@article{minitron2024,
+ title={Compact Language Models via Pruning and Knowledge Distillation},
+ author={Saurav Muralidharan and Sharath Turuvekere Sreenivas and Raviraj Joshi and Marcin Chochowski and Mostofa Patwary and Mohammad Shoeybi and Bryan Catanzaro and Jan Kautz and Pavlo Molchanov},
+ journal={arXiv preprint arXiv:2407.14679},
+ year={2024},
+ url={https://arxiv.org/abs/2407.14679},
+}
+```
+
+## NemotronConfig
+
+[[autodoc]] NemotronConfig
+
+
+## NemotronModel
+
+[[autodoc]] NemotronModel
+ - forward
+
+
+## NemotronForCausalLM
+
+[[autodoc]] NemotronForCausalLM
+ - forward
+
+## NemotronForSequenceClassification
+
+[[autodoc]] NemotronForSequenceClassification
+ - forward
+
+
+## NemotronForQuestionAnswering
+
+[[autodoc]] NemotronForQuestionAnswering
+ - forward
+
+
+## NemotronForTokenClassification
+
+[[autodoc]] NemotronForTokenClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nezha.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nezha.md
new file mode 100644
index 0000000000000000000000000000000000000000..976722592cad22b1b63316bfe0c7f4bd2932a1c8
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nezha.md
@@ -0,0 +1,96 @@
+
+
+# Nezha
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The Nezha model was proposed in [NEZHA: Neural Contextualized Representation for Chinese Language Understanding](https://arxiv.org/abs/1909.00204) by Junqiu Wei et al.
+
+The abstract from the paper is the following:
+
+*The pre-trained language models have achieved great successes in various natural language understanding (NLU) tasks
+due to its capacity to capture the deep contextualized information in text by pre-training on large-scale corpora.
+In this technical report, we present our practice of pre-training language models named NEZHA (NEural contextualiZed
+representation for CHinese lAnguage understanding) on Chinese corpora and finetuning for the Chinese NLU tasks.
+The current version of NEZHA is based on BERT with a collection of proven improvements, which include Functional
+Relative Positional Encoding as an effective positional encoding scheme, Whole Word Masking strategy,
+Mixed Precision Training and the LAMB Optimizer in training the models. The experimental results show that NEZHA
+achieves the state-of-the-art performances when finetuned on several representative Chinese tasks, including
+named entity recognition (People's Daily NER), sentence matching (LCQMC), Chinese sentiment classification (ChnSenti)
+and natural language inference (XNLI).*
+
+This model was contributed by [sijunhe](https://huggingface.co/sijunhe). The original code can be found [here](https://github.com/huawei-noah/Pretrained-Language-Model/tree/master/NEZHA-PyTorch).
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## NezhaConfig
+
+[[autodoc]] NezhaConfig
+
+## NezhaModel
+
+[[autodoc]] NezhaModel
+ - forward
+
+## NezhaForPreTraining
+
+[[autodoc]] NezhaForPreTraining
+ - forward
+
+## NezhaForMaskedLM
+
+[[autodoc]] NezhaForMaskedLM
+ - forward
+
+## NezhaForNextSentencePrediction
+
+[[autodoc]] NezhaForNextSentencePrediction
+ - forward
+
+## NezhaForSequenceClassification
+
+[[autodoc]] NezhaForSequenceClassification
+ - forward
+
+## NezhaForMultipleChoice
+
+[[autodoc]] NezhaForMultipleChoice
+ - forward
+
+## NezhaForTokenClassification
+
+[[autodoc]] NezhaForTokenClassification
+ - forward
+
+## NezhaForQuestionAnswering
+
+[[autodoc]] NezhaForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nllb-moe.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nllb-moe.md
new file mode 100644
index 0000000000000000000000000000000000000000..5c283fb3f0e1b1687aab054fc0d204beba6491dd
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nllb-moe.md
@@ -0,0 +1,134 @@
+
+
+# NLLB-MOE
+
+
+## Overview
+
+The NLLB model was presented in [No Language Left Behind: Scaling Human-Centered Machine Translation](https://arxiv.org/abs/2207.04672) by Marta R. Costa-jussà, James Cross, Onur Çelebi,
+Maha Elbayad, Kenneth Heafield, Kevin Heffernan, Elahe Kalbassi, Janice Lam, Daniel Licht, Jean Maillard, Anna Sun, Skyler Wang, Guillaume Wenzek, Al Youngblood, Bapi Akula,
+Loic Barrault, Gabriel Mejia Gonzalez, Prangthip Hansanti, John Hoffman, Semarley Jarrett, Kaushik Ram Sadagopan, Dirk Rowe, Shannon Spruit, Chau Tran, Pierre Andrews,
+Necip Fazil Ayan, Shruti Bhosale, Sergey Edunov, Angela Fan, Cynthia Gao, Vedanuj Goswami, Francisco Guzmán, Philipp Koehn, Alexandre Mourachko, Christophe Ropers,
+Safiyyah Saleem, Holger Schwenk, and Jeff Wang.
+
+The abstract of the paper is the following:
+
+*Driven by the goal of eradicating language barriers on a global scale, machine translation has solidified itself as a key focus of artificial intelligence research today.
+However, such efforts have coalesced around a small subset of languages, leaving behind the vast majority of mostly low-resource languages. What does it take to break the
+200 language barrier while ensuring safe, high quality results, all while keeping ethical considerations in mind? In No Language Left Behind, we took on this challenge by
+first contextualizing the need for low-resource language translation support through exploratory interviews with native speakers. Then, we created datasets and models aimed
+at narrowing the performance gap between low and high-resource languages. More specifically, we developed a conditional compute model based on Sparsely Gated Mixture of
+Experts that is trained on data obtained with novel and effective data mining techniques tailored for low-resource languages. We propose multiple architectural and training
+improvements to counteract overfitting while training on thousands of tasks. Critically, we evaluated the performance of over 40,000 different translation directions using
+a human-translated benchmark, Flores-200, and combined human evaluation with a novel toxicity benchmark covering all languages in Flores-200 to assess translation safety.
+Our model achieves an improvement of 44% BLEU relative to the previous state-of-the-art, laying important groundwork towards realizing a universal translation system.*
+
+This model was contributed by [Arthur Zucker](https://huggingface.co/ArthurZ).
+The original code can be found [here](https://github.com/facebookresearch/fairseq).
+
+## Usage tips
+
+- M2M100ForConditionalGeneration is the base model for both NLLB and NLLB MoE
+- The NLLB-MoE is very similar to the NLLB model, but it's feed forward layer is based on the implementation of SwitchTransformers.
+- The tokenizer is the same as the NLLB models.
+
+## Implementation differences with SwitchTransformers
+
+The biggest difference is the way the tokens are routed. NLLB-MoE uses a `top-2-gate` which means that for each input, only the top two experts are selected based on the
+highest predicted probabilities from the gating network, and the remaining experts are ignored. In `SwitchTransformers`, only the top-1 probabilities are computed,
+which means that tokens have less probability of being forwarded. Moreover, if a token is not routed to any expert, `SwitchTransformers` still adds its unmodified hidden
+states (kind of like a residual connection) while they are masked in `NLLB`'s top-2 routing mechanism.
+
+## Generating with NLLB-MoE
+
+The available checkpoints require around 350GB of storage. Make sure to use `accelerate` if you do not have enough RAM on your machine.
+
+While generating the target text set the `forced_bos_token_id` to the target language id. The following
+example shows how to translate English to French using the *facebook/nllb-200-distilled-600M* model.
+
+Note that we're using the BCP-47 code for French `fra_Latn`. See [here](https://github.com/facebookresearch/flores/blob/main/flores200/README.md#languages-in-flores-200)
+for the list of all BCP-47 in the Flores 200 dataset.
+
+```python
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/nllb-moe-54b")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/nllb-moe-54b")
+
+>>> article = "Previously, Ring's CEO, Jamie Siminoff, remarked the company started when his doorbell wasn't audible from his shop in his garage."
+>>> inputs = tokenizer(article, return_tensors="pt")
+
+>>> translated_tokens = model.generate(
+... **inputs, forced_bos_token_id=tokenizer.lang_code_to_id["fra_Latn"], max_length=50
+... )
+>>> tokenizer.batch_decode(translated_tokens, skip_special_tokens=True)[0]
+"Auparavant, le PDG de Ring, Jamie Siminoff, a fait remarquer que la société avait commencé lorsque sa sonnette n'était pas audible depuis son magasin dans son garage."
+```
+
+### Generating from any other language than English
+
+English (`eng_Latn`) is set as the default language from which to translate. In order to specify that you'd like to translate from a different language,
+you should specify the BCP-47 code in the `src_lang` keyword argument of the tokenizer initialization.
+
+See example below for a translation from romanian to german:
+
+```python
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/nllb-moe-54b", src_lang="ron_Latn")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/nllb-moe-54b")
+
+>>> article = "Şeful ONU spune că nu există o soluţie militară în Siria"
+>>> inputs = tokenizer(article, return_tensors="pt")
+
+>>> translated_tokens = model.generate(
+... **inputs, forced_bos_token_id=tokenizer.lang_code_to_id["deu_Latn"], max_length=30
+... )
+>>> tokenizer.batch_decode(translated_tokens, skip_special_tokens=True)[0]
+```
+
+## Resources
+
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+
+## NllbMoeConfig
+
+[[autodoc]] NllbMoeConfig
+
+## NllbMoeTop2Router
+
+[[autodoc]] NllbMoeTop2Router
+ - route_tokens
+ - forward
+
+## NllbMoeSparseMLP
+
+[[autodoc]] NllbMoeSparseMLP
+ - forward
+
+## NllbMoeModel
+
+[[autodoc]] NllbMoeModel
+ - forward
+
+## NllbMoeForConditionalGeneration
+
+[[autodoc]] NllbMoeForConditionalGeneration
+ - forward
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nllb.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nllb.md
new file mode 100644
index 0000000000000000000000000000000000000000..abdff7445aa34c0766886f1543fd30b02b64c4da
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nllb.md
@@ -0,0 +1,208 @@
+
+
+# NLLB
+
+## Updated tokenizer behavior
+
+**DISCLAIMER:** The default behaviour for the tokenizer was fixed and thus changed in April 2023.
+The previous version adds `[self.eos_token_id, self.cur_lang_code]` at the end of the token sequence for both target and source tokenization. This is wrong as the NLLB paper mentions (page 48, 6.1.1. Model Architecture) :
+
+*Note that we prefix the source sequence with the source language, as opposed to the target
+language as previously done in several works (Arivazhagan et al., 2019; Johnson et al.,
+2017). This is primarily because we prioritize optimizing zero-shot performance of our
+model on any pair of 200 languages at a minor cost to supervised performance.*
+
+Previous behaviour:
+
+```python
+>>> from transformers import NllbTokenizer
+
+>>> tokenizer = NllbTokenizer.from_pretrained("facebook/nllb-200-distilled-600M")
+>>> tokenizer("How was your day?").input_ids
+[13374, 1398, 4260, 4039, 248130, 2, 256047]
+
+>>> # 2: ''
+>>> # 256047 : 'eng_Latn'
+```
+New behaviour
+
+```python
+>>> from transformers import NllbTokenizer
+
+>>> tokenizer = NllbTokenizer.from_pretrained("facebook/nllb-200-distilled-600M")
+>>> tokenizer("How was your day?").input_ids
+[256047, 13374, 1398, 4260, 4039, 248130, 2]
+ ```
+
+Enabling the old behaviour can be done as follows:
+```python
+>>> from transformers import NllbTokenizer
+
+>>> tokenizer = NllbTokenizer.from_pretrained("facebook/nllb-200-distilled-600M", legacy_behaviour=True)
+```
+
+For more details, feel free to check the linked [PR](https://github.com/huggingface/transformers/pull/22313) and [Issue](https://github.com/huggingface/transformers/issues/19943).
+
+## Overview
+
+The NLLB model was presented in [No Language Left Behind: Scaling Human-Centered Machine Translation](https://arxiv.org/abs/2207.04672) by Marta R. Costa-jussà, James Cross, Onur Çelebi,
+Maha Elbayad, Kenneth Heafield, Kevin Heffernan, Elahe Kalbassi, Janice Lam, Daniel Licht, Jean Maillard, Anna Sun, Skyler Wang, Guillaume Wenzek, Al Youngblood, Bapi Akula,
+Loic Barrault, Gabriel Mejia Gonzalez, Prangthip Hansanti, John Hoffman, Semarley Jarrett, Kaushik Ram Sadagopan, Dirk Rowe, Shannon Spruit, Chau Tran, Pierre Andrews,
+Necip Fazil Ayan, Shruti Bhosale, Sergey Edunov, Angela Fan, Cynthia Gao, Vedanuj Goswami, Francisco Guzmán, Philipp Koehn, Alexandre Mourachko, Christophe Ropers,
+Safiyyah Saleem, Holger Schwenk, and Jeff Wang.
+
+The abstract of the paper is the following:
+
+*Driven by the goal of eradicating language barriers on a global scale, machine translation has solidified itself as a key focus of artificial intelligence research today.
+However, such efforts have coalesced around a small subset of languages, leaving behind the vast majority of mostly low-resource languages. What does it take to break the
+200 language barrier while ensuring safe, high quality results, all while keeping ethical considerations in mind? In No Language Left Behind, we took on this challenge by
+first contextualizing the need for low-resource language translation support through exploratory interviews with native speakers. Then, we created datasets and models aimed
+at narrowing the performance gap between low and high-resource languages. More specifically, we developed a conditional compute model based on Sparsely Gated Mixture of
+Experts that is trained on data obtained with novel and effective data mining techniques tailored for low-resource languages. We propose multiple architectural and training
+improvements to counteract overfitting while training on thousands of tasks. Critically, we evaluated the performance of over 40,000 different translation directions using
+a human-translated benchmark, Flores-200, and combined human evaluation with a novel toxicity benchmark covering all languages in Flores-200 to assess translation safety.
+Our model achieves an improvement of 44% BLEU relative to the previous state-of-the-art, laying important groundwork towards realizing a universal translation system.*
+
+This implementation contains the dense models available on release.
+
+**The sparse model NLLB-MoE (Mixture of Expert) is now available! More details [here](nllb-moe)**
+
+This model was contributed by [Lysandre](https://huggingface.co/lysandre). The authors' code can be found [here](https://github.com/facebookresearch/fairseq/tree/nllb).
+
+## Generating with NLLB
+
+While generating the target text set the `forced_bos_token_id` to the target language id. The following
+example shows how to translate English to French using the *facebook/nllb-200-distilled-600M* model.
+
+Note that we're using the BCP-47 code for French `fra_Latn`. See [here](https://github.com/facebookresearch/flores/blob/main/flores200/README.md#languages-in-flores-200)
+for the list of all BCP-47 in the Flores 200 dataset.
+
+```python
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/nllb-200-distilled-600M")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/nllb-200-distilled-600M")
+
+>>> article = "UN Chief says there is no military solution in Syria"
+>>> inputs = tokenizer(article, return_tensors="pt")
+
+>>> translated_tokens = model.generate(
+... **inputs, forced_bos_token_id=tokenizer.convert_tokens_to_ids("fra_Latn"), max_length=30
+... )
+>>> tokenizer.batch_decode(translated_tokens, skip_special_tokens=True)[0]
+Le chef de l'ONU dit qu'il n'y a pas de solution militaire en Syrie
+```
+
+### Generating from any other language than English
+
+English (`eng_Latn`) is set as the default language from which to translate. In order to specify that you'd like to translate from a different language,
+you should specify the BCP-47 code in the `src_lang` keyword argument of the tokenizer initialization.
+
+See example below for a translation from romanian to german:
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained(
+... "facebook/nllb-200-distilled-600M", token=True, src_lang="ron_Latn"
+... )
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/nllb-200-distilled-600M", token=True)
+
+>>> article = "Şeful ONU spune că nu există o soluţie militară în Siria"
+>>> inputs = tokenizer(article, return_tensors="pt")
+
+>>> translated_tokens = model.generate(
+... **inputs, forced_bos_token_id=tokenizer.convert_tokens_to_ids("deu_Latn"), max_length=30
+... )
+>>> tokenizer.batch_decode(translated_tokens, skip_special_tokens=True)[0]
+UN-Chef sagt, es gibt keine militärische Lösung in Syrien
+```
+
+## Resources
+
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## NllbTokenizer
+
+[[autodoc]] NllbTokenizer
+ - build_inputs_with_special_tokens
+
+## NllbTokenizerFast
+
+[[autodoc]] NllbTokenizerFast
+
+## Using Flash Attention 2
+
+Flash Attention 2 is a faster, optimized version of the attention scores computation which relies on `cuda` kernels.
+
+### Installation
+
+First, check whether your hardware is compatible with Flash Attention 2. The latest list of compatible hardware can be found in the [official documentation](https://github.com/Dao-AILab/flash-attention#installation-and-features).
+
+Next, [install](https://github.com/Dao-AILab/flash-attention#installation-and-features) the latest version of Flash Attention 2:
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+### Usage
+
+To load a model using Flash Attention 2, we can pass the argument `attn_implementation="flash_attention_2"` to [`.from_pretrained`](https://huggingface.co/docs/transformers/main/en/main_classes/model#transformers.PreTrainedModel.from_pretrained). You can use either `torch.float16` or `torch.bfloat16` precision.
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/nllb-200-distilled-600M", torch_dtype=torch.float16, attn_implementation="flash_attention_2").to("cuda").eval()
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/nllb-200-distilled-600M")
+
+>>> article = "Şeful ONU spune că nu există o soluţie militară în Siria"
+>>> inputs = tokenizer(article, return_tensors="pt").to("cuda")
+
+>>> translated_tokens = model.generate(
+... **inputs, forced_bos_token_id=tokenizer.convert_tokens_to_ids("deu_Latn"), max_length=30
+... )
+>>> tokenizer.batch_decode(translated_tokens, skip_special_tokens=True)[0]
+"UN-Chef sagt, es gibt keine militärische Lösung in Syrien"
+```
+
+### Expected speedups
+
+Below is an expected speedup diagram that compares pure inference time between the native implementation and the Flash Attention 2.
+
+
+
+
+
+## Using Scaled Dot Product Attention (SDPA)
+PyTorch includes a native scaled dot-product attention (SDPA) operator as part of `torch.nn.functional`. This function
+encompasses several implementations that can be applied depending on the inputs and the hardware in use. See the
+[official documentation](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)
+or the [GPU Inference](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)
+page for more information.
+
+SDPA is used by default for `torch>=2.1.1` when an implementation is available, but you may also set
+`attn_implementation="sdpa"` in `from_pretrained()` to explicitly request SDPA to be used.
+
+```python
+from transformers import AutoModelForSeq2SeqLM
+model = AutoModelForSeq2SeqLM.from_pretrained("facebook/nllb-200-distilled-600M", torch_dtype=torch.float16, attn_implementation="sdpa")
+...
+```
+
+For the best speedups, we recommend loading the model in half-precision (e.g. `torch.float16` or `torch.bfloat16`).
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nougat.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nougat.md
new file mode 100644
index 0000000000000000000000000000000000000000..a39e74eb213ab8b195e2cce03a8f1e1a7eedfd35
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nougat.md
@@ -0,0 +1,115 @@
+
+
+# Nougat
+
+## Overview
+
+The Nougat model was proposed in [Nougat: Neural Optical Understanding for Academic Documents](https://arxiv.org/abs/2308.13418) by
+Lukas Blecher, Guillem Cucurull, Thomas Scialom, Robert Stojnic. Nougat uses the same architecture as [Donut](donut), meaning an image Transformer
+encoder and an autoregressive text Transformer decoder to translate scientific PDFs to markdown, enabling easier access to them.
+
+The abstract from the paper is the following:
+
+*Scientific knowledge is predominantly stored in books and scientific journals, often in the form of PDFs. However, the PDF format leads to a loss of semantic information, particularly for mathematical expressions. We propose Nougat (Neural Optical Understanding for Academic Documents), a Visual Transformer model that performs an Optical Character Recognition (OCR) task for processing scientific documents into a markup language, and demonstrate the effectiveness of our model on a new dataset of scientific documents. The proposed approach offers a promising solution to enhance the accessibility of scientific knowledge in the digital age, by bridging the gap between human-readable documents and machine-readable text. We release the models and code to accelerate future work on scientific text recognition.*
+
+
+
+ Nougat high-level overview. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found
+[here](https://github.com/facebookresearch/nougat).
+
+## Usage tips
+
+- The quickest way to get started with Nougat is by checking the [tutorial
+ notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Nougat), which show how to use the model
+ at inference time as well as fine-tuning on custom data.
+- Nougat is always used within the [VisionEncoderDecoder](vision-encoder-decoder) framework. The model is identical to [Donut](donut) in terms of architecture.
+
+## Inference
+
+Nougat's [`VisionEncoderDecoder`] model accepts images as input and makes use of
+[`~generation.GenerationMixin.generate`] to autoregressively generate text given the input image.
+
+The [`NougatImageProcessor`] class is responsible for preprocessing the input image and
+[`NougatTokenizerFast`] decodes the generated target tokens to the target string. The
+[`NougatProcessor`] wraps [`NougatImageProcessor`] and [`NougatTokenizerFast`] classes
+into a single instance to both extract the input features and decode the predicted token ids.
+
+- Step-by-step PDF transcription
+
+```py
+>>> from huggingface_hub import hf_hub_download
+>>> import re
+>>> from PIL import Image
+
+>>> from transformers import NougatProcessor, VisionEncoderDecoderModel
+>>> from datasets import load_dataset
+>>> import torch
+
+>>> processor = NougatProcessor.from_pretrained("facebook/nougat-base")
+>>> model = VisionEncoderDecoderModel.from_pretrained("facebook/nougat-base")
+
+>>> device = "cuda" if torch.cuda.is_available() else "cpu"
+>>> model.to(device) # doctest: +IGNORE_RESULT
+
+>>> # prepare PDF image for the model
+>>> filepath = hf_hub_download(repo_id="hf-internal-testing/fixtures_docvqa", filename="nougat_paper.png", repo_type="dataset")
+>>> image = Image.open(filepath)
+>>> pixel_values = processor(image, return_tensors="pt").pixel_values
+
+>>> # generate transcription (here we only generate 30 tokens)
+>>> outputs = model.generate(
+... pixel_values.to(device),
+... min_length=1,
+... max_new_tokens=30,
+... bad_words_ids=[[processor.tokenizer.unk_token_id]],
+... )
+
+>>> sequence = processor.batch_decode(outputs, skip_special_tokens=True)[0]
+>>> sequence = processor.post_process_generation(sequence, fix_markdown=False)
+>>> # note: we're using repr here such for the sake of printing the \n characters, feel free to just print the sequence
+>>> print(repr(sequence))
+'\n\n# Nougat: Neural Optical Understanding for Academic Documents\n\n Lukas Blecher\n\nCorrespondence to: lblecher@'
+```
+
+See the [model hub](https://huggingface.co/models?filter=nougat) to look for Nougat checkpoints.
+
+
+
+The model is identical to [Donut](donut) in terms of architecture.
+
+
+
+## NougatImageProcessor
+
+[[autodoc]] NougatImageProcessor
+ - preprocess
+
+## NougatTokenizerFast
+
+[[autodoc]] NougatTokenizerFast
+
+## NougatProcessor
+
+[[autodoc]] NougatProcessor
+ - __call__
+ - from_pretrained
+ - save_pretrained
+ - batch_decode
+ - decode
+ - post_process_generation
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nystromformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nystromformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..185c4e1f011a4fc3c4de0de2a8d86b9ed15793a0
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/nystromformer.md
@@ -0,0 +1,80 @@
+
+
+# Nyströmformer
+
+## Overview
+
+The Nyströmformer model was proposed in [*Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention*](https://arxiv.org/abs/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn
+Fung, Yin Li, and Vikas Singh.
+
+The abstract from the paper is the following:
+
+*Transformers have emerged as a powerful tool for a broad range of natural language processing tasks. A key component
+that drives the impressive performance of Transformers is the self-attention mechanism that encodes the influence or
+dependence of other tokens on each specific token. While beneficial, the quadratic complexity of self-attention on the
+input sequence length has limited its application to longer sequences -- a topic being actively studied in the
+community. To address this limitation, we propose Nyströmformer -- a model that exhibits favorable scalability as a
+function of sequence length. Our idea is based on adapting the Nyström method to approximate standard self-attention
+with O(n) complexity. The scalability of Nyströmformer enables application to longer sequences with thousands of
+tokens. We perform evaluations on multiple downstream tasks on the GLUE benchmark and IMDB reviews with standard
+sequence length, and find that our Nyströmformer performs comparably, or in a few cases, even slightly better, than
+standard self-attention. On longer sequence tasks in the Long Range Arena (LRA) benchmark, Nyströmformer performs
+favorably relative to other efficient self-attention methods. Our code is available at this https URL.*
+
+This model was contributed by [novice03](https://huggingface.co/novice03). The original code can be found [here](https://github.com/mlpen/Nystromformer).
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## NystromformerConfig
+
+[[autodoc]] NystromformerConfig
+
+## NystromformerModel
+
+[[autodoc]] NystromformerModel
+ - forward
+
+## NystromformerForMaskedLM
+
+[[autodoc]] NystromformerForMaskedLM
+ - forward
+
+## NystromformerForSequenceClassification
+
+[[autodoc]] NystromformerForSequenceClassification
+ - forward
+
+## NystromformerForMultipleChoice
+
+[[autodoc]] NystromformerForMultipleChoice
+ - forward
+
+## NystromformerForTokenClassification
+
+[[autodoc]] NystromformerForTokenClassification
+ - forward
+
+## NystromformerForQuestionAnswering
+
+[[autodoc]] NystromformerForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/olmo.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/olmo.md
new file mode 100644
index 0000000000000000000000000000000000000000..6db7d8ad5c5e8ed54ffe3333b4f2002c2d61fb2c
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/olmo.md
@@ -0,0 +1,45 @@
+
+
+# OLMo
+
+## Overview
+
+The OLMo model was proposed in [OLMo: Accelerating the Science of Language Models](https://arxiv.org/abs/2402.00838) by Dirk Groeneveld, Iz Beltagy, Pete Walsh, Akshita Bhagia, Rodney Kinney, Oyvind Tafjord, Ananya Harsh Jha, Hamish Ivison, Ian Magnusson, Yizhong Wang, Shane Arora, David Atkinson, Russell Authur, Khyathi Raghavi Chandu, Arman Cohan, Jennifer Dumas, Yanai Elazar, Yuling Gu, Jack Hessel, Tushar Khot, William Merrill, Jacob Morrison, Niklas Muennighoff, Aakanksha Naik, Crystal Nam, Matthew E. Peters, Valentina Pyatkin, Abhilasha Ravichander, Dustin Schwenk, Saurabh Shah, Will Smith, Emma Strubell, Nishant Subramani, Mitchell Wortsman, Pradeep Dasigi, Nathan Lambert, Kyle Richardson, Luke Zettlemoyer, Jesse Dodge, Kyle Lo, Luca Soldaini, Noah A. Smith, Hannaneh Hajishirzi.
+
+OLMo is a series of **O**pen **L**anguage **Mo**dels designed to enable the science of language models. The OLMo models are trained on the Dolma dataset. We release all code, checkpoints, logs (coming soon), and details involved in training these models.
+
+The abstract from the paper is the following:
+
+*Language models (LMs) have become ubiquitous in both NLP research and in commercial product offerings. As their commercial importance has surged, the most powerful models have become closed off, gated behind proprietary interfaces, with important details of their training data, architectures, and development undisclosed. Given the importance of these details in scientifically studying these models, including their biases and potential risks, we believe it is essential for the research community to have access to powerful, truly open LMs. To this end, this technical report details the first release of OLMo, a state-of-the-art, truly Open Language Model and its framework to build and study the science of language modeling. Unlike most prior efforts that have only released model weights and inference code, we release OLMo and the whole framework, including training data and training and evaluation code. We hope this release will empower and strengthen the open research community and inspire a new wave of innovation.*
+
+This model was contributed by [shanearora](https://huggingface.co/shanearora).
+The original code can be found [here](https://github.com/allenai/OLMo/tree/main/olmo).
+
+
+## OlmoConfig
+
+[[autodoc]] OlmoConfig
+
+## OlmoModel
+
+[[autodoc]] OlmoModel
+ - forward
+
+## OlmoForCausalLM
+
+[[autodoc]] OlmoForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/olmo2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/olmo2.md
new file mode 100644
index 0000000000000000000000000000000000000000..8ca3326660b3f4893af25634574a36791da7b03b
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/olmo2.md
@@ -0,0 +1,46 @@
+
+
+# OLMo2
+
+## Overview
+
+The OLMo2 model is the successor of the OLMo model, which was proposed in
+[OLMo: Accelerating the Science of Language Models](https://arxiv.org/abs/2402.00838).
+
+ The architectural changes from the original OLMo model to this model are:
+
+- RMSNorm is used instead of standard layer norm.
+- Norm is applied to attention queries and keys.
+- Norm is applied after attention/feedforward layers rather than before.
+
+This model was contributed by [shanearora](https://huggingface.co/shanearora).
+The original code can be found [here](https://github.com/allenai/OLMo/tree/main/olmo).
+
+
+## Olmo2Config
+
+[[autodoc]] Olmo2Config
+
+## Olmo2Model
+
+[[autodoc]] Olmo2Model
+ - forward
+
+## Olmo2ForCausalLM
+
+[[autodoc]] Olmo2ForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/olmoe.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/olmoe.md
new file mode 100644
index 0000000000000000000000000000000000000000..5ebcf3f943b30b623bf8c0fd82dc99454fceada7
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/olmoe.md
@@ -0,0 +1,45 @@
+
+
+# OLMoE
+
+## Overview
+
+The OLMoE model was proposed in [OLMoE: Open Mixture-of-Experts Language Models](https://arxiv.org/abs/2409.02060) by Niklas Muennighoff, Luca Soldaini, Dirk Groeneveld, Kyle Lo, Jacob Morrison, Sewon Min, Weijia Shi, Pete Walsh, Oyvind Tafjord, Nathan Lambert, Yuling Gu, Shane Arora, Akshita Bhagia, Dustin Schwenk, David Wadden, Alexander Wettig, Binyuan Hui, Tim Dettmers, Douwe Kiela, Ali Farhadi, Noah A. Smith, Pang Wei Koh, Amanpreet Singh, Hannaneh Hajishirzi.
+
+OLMoE is a series of **O**pen **L**anguage **Mo**dels using sparse **M**ixture-**o**f-**E**xperts designed to enable the science of language models. We release all code, checkpoints, logs, and details involved in training these models.
+
+The abstract from the paper is the following:
+
+*We introduce OLMoE, a fully open, state-of-the-art language model leveraging sparse Mixture-of-Experts (MoE). OLMoE-1B-7B has 7 billion (B) parameters but uses only 1B per input token. We pretrain it on 5 trillion tokens and further adapt it to create OLMoE-1B-7B-Instruct. Our models outperform all available models with similar active parameters, even surpassing larger ones like Llama2-13B-Chat and DeepSeekMoE-16B. We present various experiments on MoE training, analyze routing in our model showing high specialization, and open-source all aspects of our work: model weights, training data, code, and logs.*
+
+This model was contributed by [Muennighoff](https://hf.co/Muennighoff).
+The original code can be found [here](https://github.com/allenai/OLMoE).
+
+
+## OlmoeConfig
+
+[[autodoc]] OlmoeConfig
+
+## OlmoeModel
+
+[[autodoc]] OlmoeModel
+ - forward
+
+## OlmoeForCausalLM
+
+[[autodoc]] OlmoeForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/omdet-turbo.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/omdet-turbo.md
new file mode 100644
index 0000000000000000000000000000000000000000..1e9e05a898d230c74223aa7d02dbeabfe4dfdb45
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/omdet-turbo.md
@@ -0,0 +1,164 @@
+
+
+# OmDet-Turbo
+
+## Overview
+
+The OmDet-Turbo model was proposed in [Real-time Transformer-based Open-Vocabulary Detection with Efficient Fusion Head](https://arxiv.org/abs/2403.06892) by Tiancheng Zhao, Peng Liu, Xuan He, Lu Zhang, Kyusong Lee. OmDet-Turbo incorporates components from RT-DETR and introduces a swift multimodal fusion module to achieve real-time open-vocabulary object detection capabilities while maintaining high accuracy. The base model achieves performance of up to 100.2 FPS and 53.4 AP on COCO zero-shot.
+
+The abstract from the paper is the following:
+
+*End-to-end transformer-based detectors (DETRs) have shown exceptional performance in both closed-set and open-vocabulary object detection (OVD) tasks through the integration of language modalities. However, their demanding computational requirements have hindered their practical application in real-time object detection (OD) scenarios. In this paper, we scrutinize the limitations of two leading models in the OVDEval benchmark, OmDet and Grounding-DINO, and introduce OmDet-Turbo. This novel transformer-based real-time OVD model features an innovative Efficient Fusion Head (EFH) module designed to alleviate the bottlenecks observed in OmDet and Grounding-DINO. Notably, OmDet-Turbo-Base achieves a 100.2 frames per second (FPS) with TensorRT and language cache techniques applied. Notably, in zero-shot scenarios on COCO and LVIS datasets, OmDet-Turbo achieves performance levels nearly on par with current state-of-the-art supervised models. Furthermore, it establishes new state-of-the-art benchmarks on ODinW and OVDEval, boasting an AP of 30.1 and an NMS-AP of 26.86, respectively. The practicality of OmDet-Turbo in industrial applications is underscored by its exceptional performance on benchmark datasets and superior inference speed, positioning it as a compelling choice for real-time object detection tasks.*
+
+
+
+ OmDet-Turbo architecture overview. Taken from the original paper.
+
+This model was contributed by [yonigozlan](https://huggingface.co/yonigozlan).
+The original code can be found [here](https://github.com/om-ai-lab/OmDet).
+
+## Usage tips
+
+One unique property of OmDet-Turbo compared to other zero-shot object detection models, such as [Grounding DINO](grounding-dino), is the decoupled classes and prompt embedding structure that allows caching of text embeddings. This means that the model needs both classes and task as inputs, where classes is a list of objects we want to detect and task is the grounded text used to guide open-vocabulary detection. This approach limits the scope of the open-vocabulary detection and makes the decoding process faster.
+
+[`OmDetTurboProcessor`] is used to prepare the classes, task and image triplet. The task input is optional, and when not provided, it will default to `"Detect [class1], [class2], [class3], ..."`. To process the results from the model, one can use `post_process_grounded_object_detection` from [`OmDetTurboProcessor`]. Notably, this function takes in the input classes, as unlike other zero-shot object detection models, the decoupling of classes and task embeddings means that no decoding of the predicted class embeddings is needed in the post-processing step, and the predicted classes can be matched to the inputted ones directly.
+
+## Usage example
+
+### Single image inference
+
+Here's how to load the model and prepare the inputs to perform zero-shot object detection on a single image:
+
+```python
+import requests
+from PIL import Image
+
+from transformers import AutoProcessor, OmDetTurboForObjectDetection
+
+processor = AutoProcessor.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+model = OmDetTurboForObjectDetection.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+classes = ["cat", "remote"]
+inputs = processor(image, text=classes, return_tensors="pt")
+
+outputs = model(**inputs)
+
+# convert outputs (bounding boxes and class logits)
+results = processor.post_process_grounded_object_detection(
+ outputs,
+ classes=classes,
+ target_sizes=[image.size[::-1]],
+ score_threshold=0.3,
+ nms_threshold=0.3,
+)[0]
+for score, class_name, box in zip(
+ results["scores"], results["classes"], results["boxes"]
+):
+ box = [round(i, 1) for i in box.tolist()]
+ print(
+ f"Detected {class_name} with confidence "
+ f"{round(score.item(), 2)} at location {box}"
+ )
+```
+
+### Multi image inference
+
+OmDet-Turbo can perform batched multi-image inference, with support for different text prompts and classes in the same batch:
+
+```python
+>>> import torch
+>>> import requests
+>>> from io import BytesIO
+>>> from PIL import Image
+>>> from transformers import AutoProcessor, OmDetTurboForObjectDetection
+
+>>> processor = AutoProcessor.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+>>> model = OmDetTurboForObjectDetection.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+
+>>> url1 = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image1 = Image.open(BytesIO(requests.get(url1).content)).convert("RGB")
+>>> classes1 = ["cat", "remote"]
+>>> task1 = "Detect {}.".format(", ".join(classes1))
+
+>>> url2 = "http://images.cocodataset.org/train2017/000000257813.jpg"
+>>> image2 = Image.open(BytesIO(requests.get(url2).content)).convert("RGB")
+>>> classes2 = ["boat"]
+>>> task2 = "Detect everything that looks like a boat."
+
+>>> url3 = "https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg"
+>>> image3 = Image.open(BytesIO(requests.get(url3).content)).convert("RGB")
+>>> classes3 = ["statue", "trees"]
+>>> task3 = "Focus on the foreground, detect statue and trees."
+
+>>> inputs = processor(
+... images=[image1, image2, image3],
+... text=[classes1, classes2, classes3],
+... task=[task1, task2, task3],
+... return_tensors="pt",
+... )
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> # convert outputs (bounding boxes and class logits)
+>>> results = processor.post_process_grounded_object_detection(
+... outputs,
+... classes=[classes1, classes2, classes3],
+... target_sizes=[image1.size[::-1], image2.size[::-1], image3.size[::-1]],
+... score_threshold=0.2,
+... nms_threshold=0.3,
+... )
+
+>>> for i, result in enumerate(results):
+... for score, class_name, box in zip(
+... result["scores"], result["classes"], result["boxes"]
+... ):
+... box = [round(i, 1) for i in box.tolist()]
+... print(
+... f"Detected {class_name} with confidence "
+... f"{round(score.item(), 2)} at location {box} in image {i}"
+... )
+Detected remote with confidence 0.77 at location [39.9, 70.4, 176.7, 118.0] in image 0
+Detected cat with confidence 0.72 at location [11.6, 54.2, 314.8, 474.0] in image 0
+Detected remote with confidence 0.56 at location [333.4, 75.8, 370.7, 187.0] in image 0
+Detected cat with confidence 0.55 at location [345.2, 24.0, 639.8, 371.7] in image 0
+Detected boat with confidence 0.32 at location [146.9, 219.8, 209.6, 250.7] in image 1
+Detected boat with confidence 0.3 at location [319.1, 223.2, 403.2, 238.4] in image 1
+Detected boat with confidence 0.27 at location [37.7, 220.3, 84.0, 235.9] in image 1
+Detected boat with confidence 0.22 at location [407.9, 207.0, 441.7, 220.2] in image 1
+Detected statue with confidence 0.73 at location [544.7, 210.2, 651.9, 502.8] in image 2
+Detected trees with confidence 0.25 at location [3.9, 584.3, 391.4, 785.6] in image 2
+Detected trees with confidence 0.25 at location [1.4, 621.2, 118.2, 787.8] in image 2
+Detected statue with confidence 0.2 at location [428.1, 205.5, 767.3, 759.5] in image 2
+
+```
+
+## OmDetTurboConfig
+
+[[autodoc]] OmDetTurboConfig
+
+## OmDetTurboProcessor
+
+[[autodoc]] OmDetTurboProcessor
+ - post_process_grounded_object_detection
+
+## OmDetTurboForObjectDetection
+
+[[autodoc]] OmDetTurboForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/oneformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/oneformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..0132a600ccc5e531b9a1d1110ff9ced91c8414ac
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/oneformer.md
@@ -0,0 +1,86 @@
+
+
+# OneFormer
+
+## Overview
+
+The OneFormer model was proposed in [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi. OneFormer is a universal image segmentation framework that can be trained on a single panoptic dataset to perform semantic, instance, and panoptic segmentation tasks. OneFormer uses a task token to condition the model on the task in focus, making the architecture task-guided for training, and task-dynamic for inference.
+
+
+
+The abstract from the paper is the following:
+
+*Universal Image Segmentation is not a new concept. Past attempts to unify image segmentation in the last decades include scene parsing, panoptic segmentation, and, more recently, new panoptic architectures. However, such panoptic architectures do not truly unify image segmentation because they need to be trained individually on the semantic, instance, or panoptic segmentation to achieve the best performance. Ideally, a truly universal framework should be trained only once and achieve SOTA performance across all three image segmentation tasks. To that end, we propose OneFormer, a universal image segmentation framework that unifies segmentation with a multi-task train-once design. We first propose a task-conditioned joint training strategy that enables training on ground truths of each domain (semantic, instance, and panoptic segmentation) within a single multi-task training process. Secondly, we introduce a task token to condition our model on the task at hand, making our model task-dynamic to support multi-task training and inference. Thirdly, we propose using a query-text contrastive loss during training to establish better inter-task and inter-class distinctions. Notably, our single OneFormer model outperforms specialized Mask2Former models across all three segmentation tasks on ADE20k, CityScapes, and COCO, despite the latter being trained on each of the three tasks individually with three times the resources. With new ConvNeXt and DiNAT backbones, we observe even more performance improvement. We believe OneFormer is a significant step towards making image segmentation more universal and accessible.*
+
+The figure below illustrates the architecture of OneFormer. Taken from the [original paper](https://arxiv.org/abs/2211.06220).
+
+
+
+This model was contributed by [Jitesh Jain](https://huggingface.co/praeclarumjj3). The original code can be found [here](https://github.com/SHI-Labs/OneFormer).
+
+## Usage tips
+
+- OneFormer requires two inputs during inference: *image* and *task token*.
+- During training, OneFormer only uses panoptic annotations.
+- If you want to train the model in a distributed environment across multiple nodes, then one should update the
+ `get_num_masks` function inside in the `OneFormerLoss` class of `modeling_oneformer.py`. When training on multiple nodes, this should be
+ set to the average number of target masks across all nodes, as can be seen in the original implementation [here](https://github.com/SHI-Labs/OneFormer/blob/33ebb56ed34f970a30ae103e786c0cb64c653d9a/oneformer/modeling/criterion.py#L287).
+- One can use [`OneFormerProcessor`] to prepare input images and task inputs for the model and optional targets for the model. [`OneFormerProcessor`] wraps [`OneFormerImageProcessor`] and [`CLIPTokenizer`] into a single instance to both prepare the images and encode the task inputs.
+- To get the final segmentation, depending on the task, you can call [`~OneFormerProcessor.post_process_semantic_segmentation`] or [`~OneFormerImageProcessor.post_process_instance_segmentation`] or [`~OneFormerImageProcessor.post_process_panoptic_segmentation`]. All three tasks can be solved using [`OneFormerForUniversalSegmentation`] output, panoptic segmentation accepts an optional `label_ids_to_fuse` argument to fuse instances of the target object/s (e.g. sky) together.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with OneFormer.
+
+- Demo notebooks regarding inference + fine-tuning on custom data can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/OneFormer).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we will review it.
+The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## OneFormer specific outputs
+
+[[autodoc]] models.oneformer.modeling_oneformer.OneFormerModelOutput
+
+[[autodoc]] models.oneformer.modeling_oneformer.OneFormerForUniversalSegmentationOutput
+
+## OneFormerConfig
+
+[[autodoc]] OneFormerConfig
+
+## OneFormerImageProcessor
+
+[[autodoc]] OneFormerImageProcessor
+ - preprocess
+ - encode_inputs
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## OneFormerProcessor
+
+[[autodoc]] OneFormerProcessor
+
+## OneFormerModel
+
+[[autodoc]] OneFormerModel
+ - forward
+
+## OneFormerForUniversalSegmentation
+
+[[autodoc]] OneFormerForUniversalSegmentation
+ - forward
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/open-llama.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/open-llama.md
new file mode 100644
index 0000000000000000000000000000000000000000..01170e7e3be60ffb7e5fe597457b7b130178539c
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/open-llama.md
@@ -0,0 +1,61 @@
+
+
+# Open-Llama
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.31.0.
+You can do so by running the following command: `pip install -U transformers==4.31.0`.
+
+
+
+
+
+This model differs from the [OpenLLaMA models](https://huggingface.co/models?search=openllama) on the Hugging Face Hub, which primarily use the [LLaMA](llama) architecture.
+
+
+
+## Overview
+
+The Open-Llama model was proposed in the open source Open-Llama project by community developer s-JoL.
+
+The model is mainly based on LLaMA with some modifications, incorporating memory-efficient attention from Xformers, stable embedding from Bloom, and shared input-output embedding from PaLM.
+And the model is pre-trained on both Chinese and English, which gives it better performance on Chinese language tasks.
+
+This model was contributed by [s-JoL](https://huggingface.co/s-JoL).
+The original code was released on GitHub by [s-JoL](https://github.com/s-JoL), but is now removed.
+
+## OpenLlamaConfig
+
+[[autodoc]] OpenLlamaConfig
+
+## OpenLlamaModel
+
+[[autodoc]] OpenLlamaModel
+ - forward
+
+## OpenLlamaForCausalLM
+
+[[autodoc]] OpenLlamaForCausalLM
+ - forward
+
+## OpenLlamaForSequenceClassification
+
+[[autodoc]] OpenLlamaForSequenceClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/openai-gpt.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/openai-gpt.md
new file mode 100644
index 0000000000000000000000000000000000000000..09277858aa3bc062aa3ffd94ebe1c15e4bf0b763
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/openai-gpt.md
@@ -0,0 +1,167 @@
+
+
+# OpenAI GPT
+
+
+
+## Overview
+
+OpenAI GPT model was proposed in [Improving Language Understanding by Generative Pre-Training](https://s3-us-west-2.amazonaws.com/openai-assets/research-covers/language-unsupervised/language_understanding_paper.pdf)
+by Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever. It's a causal (unidirectional) transformer
+pre-trained using language modeling on a large corpus with long range dependencies, the Toronto Book Corpus.
+
+The abstract from the paper is the following:
+
+*Natural language understanding comprises a wide range of diverse tasks such as textual entailment, question answering,
+semantic similarity assessment, and document classification. Although large unlabeled text corpora are abundant,
+labeled data for learning these specific tasks is scarce, making it challenging for discriminatively trained models to
+perform adequately. We demonstrate that large gains on these tasks can be realized by generative pretraining of a
+language model on a diverse corpus of unlabeled text, followed by discriminative fine-tuning on each specific task. In
+contrast to previous approaches, we make use of task-aware input transformations during fine-tuning to achieve
+effective transfer while requiring minimal changes to the model architecture. We demonstrate the effectiveness of our
+approach on a wide range of benchmarks for natural language understanding. Our general task-agnostic model outperforms
+discriminatively trained models that use architectures specifically crafted for each task, significantly improving upon
+the state of the art in 9 out of the 12 tasks studied.*
+
+[Write With Transformer](https://transformer.huggingface.co/doc/gpt) is a webapp created and hosted by Hugging Face
+showcasing the generative capabilities of several models. GPT is one of them.
+
+This model was contributed by [thomwolf](https://huggingface.co/thomwolf). The original code can be found [here](https://github.com/openai/finetune-transformer-lm).
+
+## Usage tips
+
+- GPT is a model with absolute position embeddings so it's usually advised to pad the inputs on the right rather than
+ the left.
+- GPT was trained with a causal language modeling (CLM) objective and is therefore powerful at predicting the next
+ token in a sequence. Leveraging this feature allows GPT-2 to generate syntactically coherent text as it can be
+ observed in the *run_generation.py* example script.
+
+
+Note:
+
+If you want to reproduce the original tokenization process of the *OpenAI GPT* paper, you will need to install `ftfy`
+and `SpaCy`:
+
+```bash
+pip install spacy ftfy==4.4.3
+python -m spacy download en
+```
+
+If you don't install `ftfy` and `SpaCy`, the [`OpenAIGPTTokenizer`] will default to tokenize
+using BERT's `BasicTokenizer` followed by Byte-Pair Encoding (which should be fine for most usage, don't worry).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with OpenAI GPT. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- A blog post on [outperforming OpenAI GPT-3 with SetFit for text-classification](https://www.philschmid.de/getting-started-setfit).
+- See also: [Text classification task guide](../tasks/sequence_classification)
+
+
+
+- A blog on how to [Finetune a non-English GPT-2 Model with Hugging Face](https://www.philschmid.de/fine-tune-a-non-english-gpt-2-model-with-huggingface).
+- A blog on [How to generate text: using different decoding methods for language generation with Transformers](https://huggingface.co/blog/how-to-generate) with GPT-2.
+- A blog on [Training CodeParrot 🦜 from Scratch](https://huggingface.co/blog/codeparrot), a large GPT-2 model.
+- A blog on [Faster Text Generation with TensorFlow and XLA](https://huggingface.co/blog/tf-xla-generate) with GPT-2.
+- A blog on [How to train a Language Model with Megatron-LM](https://huggingface.co/blog/megatron-training) with a GPT-2 model.
+- A notebook on how to [finetune GPT2 to generate lyrics in the style of your favorite artist](https://colab.research.google.com/github/AlekseyKorshuk/huggingartists/blob/master/huggingartists-demo.ipynb). 🌎
+- A notebook on how to [finetune GPT2 to generate tweets in the style of your favorite Twitter user](https://colab.research.google.com/github/borisdayma/huggingtweets/blob/master/huggingtweets-demo.ipynb). 🌎
+- [Causal language modeling](https://huggingface.co/course/en/chapter7/6?fw=pt#training-a-causal-language-model-from-scratch) chapter of the 🤗 Hugging Face Course.
+- [`OpenAIGPTLMHeadModel`] is supported by this [causal language modeling example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/language-modeling#gpt-2gpt-and-causal-language-modeling), [text generation example script](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-generation/run_generation.py) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb).
+- [`TFOpenAIGPTLMHeadModel`] is supported by this [causal language modeling example script](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/language-modeling#run_clmpy) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb).
+- See also: [Causal language modeling task guide](../tasks/language_modeling)
+
+
+
+- A course material on [Byte-Pair Encoding tokenization](https://huggingface.co/course/en/chapter6/5).
+
+## OpenAIGPTConfig
+
+[[autodoc]] OpenAIGPTConfig
+
+## OpenAIGPTTokenizer
+
+[[autodoc]] OpenAIGPTTokenizer
+ - save_vocabulary
+
+## OpenAIGPTTokenizerFast
+
+[[autodoc]] OpenAIGPTTokenizerFast
+
+## OpenAI specific outputs
+
+[[autodoc]] models.openai.modeling_openai.OpenAIGPTDoubleHeadsModelOutput
+
+[[autodoc]] models.openai.modeling_tf_openai.TFOpenAIGPTDoubleHeadsModelOutput
+
+
+
+
+## OpenAIGPTModel
+
+[[autodoc]] OpenAIGPTModel
+ - forward
+
+## OpenAIGPTLMHeadModel
+
+[[autodoc]] OpenAIGPTLMHeadModel
+ - forward
+
+## OpenAIGPTDoubleHeadsModel
+
+[[autodoc]] OpenAIGPTDoubleHeadsModel
+ - forward
+
+## OpenAIGPTForSequenceClassification
+
+[[autodoc]] OpenAIGPTForSequenceClassification
+ - forward
+
+
+
+
+## TFOpenAIGPTModel
+
+[[autodoc]] TFOpenAIGPTModel
+ - call
+
+## TFOpenAIGPTLMHeadModel
+
+[[autodoc]] TFOpenAIGPTLMHeadModel
+ - call
+
+## TFOpenAIGPTDoubleHeadsModel
+
+[[autodoc]] TFOpenAIGPTDoubleHeadsModel
+ - call
+
+## TFOpenAIGPTForSequenceClassification
+
+[[autodoc]] TFOpenAIGPTForSequenceClassification
+ - call
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/opt.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/opt.md
new file mode 100644
index 0000000000000000000000000000000000000000..c82064bae894f7f56fe1a4304cac6ef0fb02326e
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/opt.md
@@ -0,0 +1,235 @@
+
+
+# OPT
+
+## Overview
+
+The OPT model was proposed in [Open Pre-trained Transformer Language Models](https://arxiv.org/pdf/2205.01068) by Meta AI.
+OPT is a series of open-sourced large causal language models which perform similar in performance to GPT3.
+
+The abstract from the paper is the following:
+
+*Large language models, which are often trained for hundreds of thousands of compute days, have shown remarkable capabilities for zero- and few-shot learning. Given their computational cost, these models are difficult to replicate without significant capital. For the few that are available through APIs, no access is granted to the full model weights, making them difficult to study. We present Open Pre-trained Transformers (OPT), a suite of decoder-only pre-trained transformers ranging from 125M to 175B parameters, which we aim to fully and responsibly share with interested researchers. We show that OPT-175B is comparable to GPT-3, while requiring only 1/7th the carbon footprint to develop. We are also releasing our logbook detailing the infrastructure challenges we faced, along with code for experimenting with all of the released models.*
+
+This model was contributed by [Arthur Zucker](https://huggingface.co/ArthurZ), [Younes Belkada](https://huggingface.co/ybelkada), and [Patrick Von Platen](https://huggingface.co/patrickvonplaten).
+The original code can be found [here](https://github.com/facebookresearch/metaseq).
+
+Tips:
+- OPT has the same architecture as [`BartDecoder`].
+- Contrary to GPT2, OPT adds the EOS token `` to the beginning of every prompt.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with OPT. If you're
+interested in submitting a resource to be included here, please feel free to open a Pull Request and we will review it.
+The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- A notebook on [fine-tuning OPT with PEFT, bitsandbytes, and Transformers](https://colab.research.google.com/drive/1jCkpikz0J2o20FBQmYmAGdiKmJGOMo-o?usp=sharing). 🌎
+- A blog post on [decoding strategies with OPT](https://huggingface.co/blog/introducing-csearch#62-example-two---opt).
+- [Causal language modeling](https://huggingface.co/course/en/chapter7/6?fw=pt#training-a-causal-language-model-from-scratch) chapter of the 🤗 Hugging Face Course.
+- [`OPTForCausalLM`] is supported by this [causal language modeling example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/language-modeling#gpt-2gpt-and-causal-language-modeling) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb).
+- [`TFOPTForCausalLM`] is supported by this [causal language modeling example script](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/language-modeling#run_clmpy) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb).
+- [`FlaxOPTForCausalLM`] is supported by this [causal language modeling example script](https://github.com/huggingface/transformers/tree/main/examples/flax/language-modeling#causal-language-modeling).
+
+
+
+- [Text classification task guide](sequence_classification.md)
+- [`OPTForSequenceClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification.ipynb).
+
+
+
+- [`OPTForQuestionAnswering`] is supported by this [question answering example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb).
+- [Question answering](https://huggingface.co/course/chapter7/7?fw=pt) chapter
+ of the 🤗 Hugging Face Course.
+
+⚡️ Inference
+
+- A blog post on [How 🤗 Accelerate runs very large models thanks to PyTorch](https://huggingface.co/blog/accelerate-large-models) with OPT.
+
+
+## Combining OPT and Flash Attention 2
+
+First, make sure to install the latest version of Flash Attention 2 to include the sliding window attention feature.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Make also sure that you have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of flash-attn repository. Make also sure to load your model in half-precision (e.g. `torch.float16``)
+
+To load and run a model using Flash Attention 2, refer to the snippet below:
+
+```python
+>>> import torch
+>>> from transformers import OPTForCausalLM, GPT2Tokenizer
+>>> device = "cuda" # the device to load the model onto
+
+>>> model = OPTForCausalLM.from_pretrained("facebook/opt-350m", torch_dtype=torch.float16, attn_implementation="flash_attention_2")
+>>> tokenizer = GPT2Tokenizer.from_pretrained("facebook/opt-350m")
+
+>>> prompt = ("A chat between a curious human and the Statue of Liberty.\n\nHuman: What is your name?\nStatue: I am the "
+ "Statue of Liberty.\nHuman: Where do you live?\nStatue: New York City.\nHuman: How long have you lived "
+ "there?")
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to(device)
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=30, do_sample=False)
+>>> tokenizer.batch_decode(generated_ids)[0]
+'A chat between a curious human and the Statue of Liberty.\n\nHuman: What is your name?\nStatue: I am the Statue of Liberty.\nHuman: Where do you live?\nStatue: New York City.\nHuman: How long have you lived there?\nStatue: I have lived here for about a year.\nHuman: What is your favorite place to eat?\nStatue: I love'
+```
+
+### Expected speedups
+
+Below is an expected speedup diagram that compares pure inference time between the native implementation in transformers using `facebook/opt-2.7b` checkpoint and the Flash Attention 2 version of the model using two different sequence lengths.
+
+
+
+
+
+Below is an expected speedup diagram that compares pure inference time between the native implementation in transformers using `facebook/opt-350m` checkpoint and the Flash Attention 2 version of the model using two different sequence lengths.
+
+
+
+
+
+
+### Using Scaled Dot Product Attention (SDPA)
+PyTorch includes a native scaled dot-product attention (SDPA) operator as part of `torch.nn.functional`. This function
+encompasses several implementations that can be applied depending on the inputs and the hardware in use. See the
+[official documentation](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)
+or the [GPU Inference](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)
+page for more information.
+
+SDPA is used by default for `torch>=2.1.1` when an implementation is available, but you may also set
+`attn_implementation="sdpa"` in `from_pretrained()` to explicitly request SDPA to be used.
+
+```python
+from transformers import OPTForCausalLM
+model = OPTForCausalLM.from_pretrained("facebook/opt-350m", torch_dtype=torch.float16, attn_implementation="sdpa")
+...
+```
+
+For the best speedups, we recommend loading the model in half-precision (e.g. `torch.float16` or `torch.bfloat16`).
+
+On a local benchmark (L40S-45GB, PyTorch 2.4.0, OS Debian GNU/Linux 11) using `float16` with
+[facebook/opt-350m](https://huggingface.co/facebook/opt-350m), we saw the
+following speedups during training and inference.
+
+### Training
+
+| batch_size | seq_len | Time per batch (eager - s) | Time per batch (sdpa - s) | Speedup (%) | Eager peak mem (MB) | sdpa peak mem (MB) | Mem saving (%) |
+|--------------:|-----------:|:------------------------------|-----------------------------:|:---------------|:-----------------------|----------------------:|:------------------|
+| 1 | 128 | 0.047 | 0.037 | 26.360 | 1474.611 | 1474.32 | 0.019 |
+| 1 | 256 | 0.046 | 0.037 | 24.335 | 1498.541 | 1499.49 | -0.063 |
+| 1 | 512 | 0.046 | 0.037 | 24.959 | 1973.544 | 1551.35 | 27.215 |
+| 1 | 1024 | 0.062 | 0.038 | 65.135 | 4867.113 | 1698.35 | 186.578 |
+| 1 | 2048 | 0.230 | 0.039 | 483.933 | 15662.224 | 2715.75 | 476.718 |
+| 2 | 128 | 0.045 | 0.037 | 20.455 | 1498.164 | 1499.49 | -0.089 |
+| 2 | 256 | 0.046 | 0.037 | 24.027 | 1569.367 | 1551.35 | 1.161 |
+| 2 | 512 | 0.045 | 0.037 | 20.965 | 3257.074 | 1698.35 | 91.778 |
+| 2 | 1024 | 0.122 | 0.038 | 225.958 | 9054.405 | 2715.75 | 233.403 |
+| 2 | 2048 | 0.464 | 0.067 | 593.646 | 30572.058 | 4750.55 | 543.548 |
+| 4 | 128 | 0.045 | 0.037 | 21.918 | 1549.448 | 1551.35 | -0.123 |
+| 4 | 256 | 0.044 | 0.038 | 18.084 | 2451.768 | 1698.35 | 44.361 |
+| 4 | 512 | 0.069 | 0.037 | 84.421 | 5833.180 | 2715.75 | 114.791 |
+| 4 | 1024 | 0.262 | 0.062 | 319.475 | 17427.842 | 4750.55 | 266.860 |
+| 4 | 2048 | OOM | 0.062 | Eager OOM | OOM | 4750.55 | Eager OOM |
+| 8 | 128 | 0.044 | 0.037 | 18.436 | 2049.115 | 1697.78 | 20.694 |
+| 8 | 256 | 0.048 | 0.036 | 32.887 | 4222.567 | 2715.75 | 55.484 |
+| 8 | 512 | 0.153 | 0.06 | 154.862 | 10985.391 | 4750.55 | 131.245 |
+| 8 | 1024 | 0.526 | 0.122 | 330.697 | 34175.763 | 8821.18 | 287.428 |
+| 8 | 2048 | OOM | 0.122 | Eager OOM | OOM | 8821.18 | Eager OOM |
+
+### Inference
+
+| batch_size | seq_len | Per token latency eager (ms) | Per token latency SDPA (ms) | Speedup (%) | Mem eager (MB) | Mem BT (MB) | Mem saved (%) |
+|--------------:|-----------:|--------------------------------:|-------------------------------:|---------------:|------------------:|---------------:|-----------------:|
+| 1 | 128 | 11.634 | 8.647 | 34.546 | 717.676 | 717.674 | 0 |
+| 1 | 256 | 11.593 | 8.86 | 30.851 | 742.852 | 742.845 | 0.001 |
+| 1 | 512 | 11.515 | 8.816 | 30.614 | 798.232 | 799.593 | -0.17 |
+| 1 | 1024 | 11.556 | 8.915 | 29.628 | 917.265 | 895.538 | 2.426 |
+| 2 | 128 | 12.724 | 11.002 | 15.659 | 762.434 | 762.431 | 0 |
+| 2 | 256 | 12.704 | 11.063 | 14.83 | 816.809 | 816.733 | 0.009 |
+| 2 | 512 | 12.757 | 10.947 | 16.535 | 917.383 | 918.339 | -0.104 |
+| 2 | 1024 | 13.018 | 11.018 | 18.147 | 1162.65 | 1114.81 | 4.291 |
+| 4 | 128 | 12.739 | 10.959 | 16.243 | 856.335 | 856.483 | -0.017 |
+| 4 | 256 | 12.718 | 10.837 | 17.355 | 957.298 | 957.674 | -0.039 |
+| 4 | 512 | 12.813 | 10.822 | 18.393 | 1158.44 | 1158.45 | -0.001 |
+| 4 | 1024 | 13.416 | 11.06 | 21.301 | 1653.42 | 1557.19 | 6.18 |
+| 8 | 128 | 12.763 | 10.891 | 17.193 | 1036.13 | 1036.51 | -0.036 |
+| 8 | 256 | 12.89 | 11.104 | 16.085 | 1236.98 | 1236.87 | 0.01 |
+| 8 | 512 | 13.327 | 10.939 | 21.836 | 1642.29 | 1641.78 | 0.031 |
+| 8 | 1024 | 15.181 | 11.175 | 35.848 | 2634.98 | 2443.35 | 7.843 |
+
+## OPTConfig
+
+[[autodoc]] OPTConfig
+
+
+
+
+## OPTModel
+
+[[autodoc]] OPTModel
+ - forward
+
+## OPTForCausalLM
+
+[[autodoc]] OPTForCausalLM
+ - forward
+
+## OPTForSequenceClassification
+
+[[autodoc]] OPTForSequenceClassification
+ - forward
+
+## OPTForQuestionAnswering
+
+[[autodoc]] OPTForQuestionAnswering
+ - forward
+
+
+
+
+## TFOPTModel
+
+[[autodoc]] TFOPTModel
+ - call
+
+## TFOPTForCausalLM
+
+[[autodoc]] TFOPTForCausalLM
+ - call
+
+
+
+
+## FlaxOPTModel
+
+[[autodoc]] FlaxOPTModel
+ - __call__
+
+## FlaxOPTForCausalLM
+
+[[autodoc]] FlaxOPTForCausalLM
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/owlv2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/owlv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..1b4e92bc4eb1108b148c4c9ccc813e0a231f6940
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/owlv2.md
@@ -0,0 +1,128 @@
+
+
+# OWLv2
+
+## Overview
+
+OWLv2 was proposed in [Scaling Open-Vocabulary Object Detection](https://arxiv.org/abs/2306.09683) by Matthias Minderer, Alexey Gritsenko, Neil Houlsby. OWLv2 scales up [OWL-ViT](owlvit) using self-training, which uses an existing detector to generate pseudo-box annotations on image-text pairs. This results in large gains over the previous state-of-the-art for zero-shot object detection.
+
+The abstract from the paper is the following:
+
+*Open-vocabulary object detection has benefited greatly from pretrained vision-language models, but is still limited by the amount of available detection training data. While detection training data can be expanded by using Web image-text pairs as weak supervision, this has not been done at scales comparable to image-level pretraining. Here, we scale up detection data with self-training, which uses an existing detector to generate pseudo-box annotations on image-text pairs. Major challenges in scaling self-training are the choice of label space, pseudo-annotation filtering, and training efficiency. We present the OWLv2 model and OWL-ST self-training recipe, which address these challenges. OWLv2 surpasses the performance of previous state-of-the-art open-vocabulary detectors already at comparable training scales (~10M examples). However, with OWL-ST, we can scale to over 1B examples, yielding further large improvement: With an L/14 architecture, OWL-ST improves AP on LVIS rare classes, for which the model has seen no human box annotations, from 31.2% to 44.6% (43% relative improvement). OWL-ST unlocks Web-scale training for open-world localization, similar to what has been seen for image classification and language modelling.*
+
+
+
+ OWLv2 high-level overview. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/google-research/scenic/tree/main/scenic/projects/owl_vit).
+
+## Usage example
+
+OWLv2 is, just like its predecessor [OWL-ViT](owlvit), a zero-shot text-conditioned object detection model. OWL-ViT uses [CLIP](clip) as its multi-modal backbone, with a ViT-like Transformer to get visual features and a causal language model to get the text features. To use CLIP for detection, OWL-ViT removes the final token pooling layer of the vision model and attaches a lightweight classification and box head to each transformer output token. Open-vocabulary classification is enabled by replacing the fixed classification layer weights with the class-name embeddings obtained from the text model. The authors first train CLIP from scratch and fine-tune it end-to-end with the classification and box heads on standard detection datasets using a bipartite matching loss. One or multiple text queries per image can be used to perform zero-shot text-conditioned object detection.
+
+[`Owlv2ImageProcessor`] can be used to resize (or rescale) and normalize images for the model and [`CLIPTokenizer`] is used to encode the text. [`Owlv2Processor`] wraps [`Owlv2ImageProcessor`] and [`CLIPTokenizer`] into a single instance to both encode the text and prepare the images. The following example shows how to perform object detection using [`Owlv2Processor`] and [`Owlv2ForObjectDetection`].
+
+```python
+>>> import requests
+>>> from PIL import Image
+>>> import torch
+
+>>> from transformers import Owlv2Processor, Owlv2ForObjectDetection
+
+>>> processor = Owlv2Processor.from_pretrained("google/owlv2-base-patch16-ensemble")
+>>> model = Owlv2ForObjectDetection.from_pretrained("google/owlv2-base-patch16-ensemble")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> texts = [["a photo of a cat", "a photo of a dog"]]
+>>> inputs = processor(text=texts, images=image, return_tensors="pt")
+>>> outputs = model(**inputs)
+
+>>> # Target image sizes (height, width) to rescale box predictions [batch_size, 2]
+>>> target_sizes = torch.Tensor([image.size[::-1]])
+>>> # Convert outputs (bounding boxes and class logits) to Pascal VOC Format (xmin, ymin, xmax, ymax)
+>>> results = processor.post_process_object_detection(outputs=outputs, target_sizes=target_sizes, threshold=0.1)
+>>> i = 0 # Retrieve predictions for the first image for the corresponding text queries
+>>> text = texts[i]
+>>> boxes, scores, labels = results[i]["boxes"], results[i]["scores"], results[i]["labels"]
+>>> for box, score, label in zip(boxes, scores, labels):
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"Detected {text[label]} with confidence {round(score.item(), 3)} at location {box}")
+Detected a photo of a cat with confidence 0.614 at location [341.67, 23.39, 642.32, 371.35]
+Detected a photo of a cat with confidence 0.665 at location [6.75, 51.96, 326.62, 473.13]
+```
+
+## Resources
+
+- A demo notebook on using OWLv2 for zero- and one-shot (image-guided) object detection can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/OWLv2).
+- [Zero-shot object detection task guide](../tasks/zero_shot_object_detection)
+
+
+
+The architecture of OWLv2 is identical to [OWL-ViT](owlvit), however the object detection head now also includes an objectness classifier, which predicts the (query-agnostic) likelihood that a predicted box contains an object (as opposed to background). The objectness score can be used to rank or filter predictions independently of text queries.
+Usage of OWLv2 is identical to [OWL-ViT](owlvit) with a new, updated image processor ([`Owlv2ImageProcessor`]).
+
+
+
+## Owlv2Config
+
+[[autodoc]] Owlv2Config
+ - from_text_vision_configs
+
+## Owlv2TextConfig
+
+[[autodoc]] Owlv2TextConfig
+
+## Owlv2VisionConfig
+
+[[autodoc]] Owlv2VisionConfig
+
+## Owlv2ImageProcessor
+
+[[autodoc]] Owlv2ImageProcessor
+ - preprocess
+ - post_process_object_detection
+ - post_process_image_guided_detection
+
+## Owlv2Processor
+
+[[autodoc]] Owlv2Processor
+
+## Owlv2Model
+
+[[autodoc]] Owlv2Model
+ - forward
+ - get_text_features
+ - get_image_features
+
+## Owlv2TextModel
+
+[[autodoc]] Owlv2TextModel
+ - forward
+
+## Owlv2VisionModel
+
+[[autodoc]] Owlv2VisionModel
+ - forward
+
+## Owlv2ForObjectDetection
+
+[[autodoc]] Owlv2ForObjectDetection
+ - forward
+ - image_guided_detection
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/owlvit.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/owlvit.md
new file mode 100644
index 0000000000000000000000000000000000000000..c40d3a9e7a17fa855c7908c131ad9fe76d6b2145
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/owlvit.md
@@ -0,0 +1,126 @@
+
+
+# OWL-ViT
+
+## Overview
+
+The OWL-ViT (short for Vision Transformer for Open-World Localization) was proposed in [Simple Open-Vocabulary Object Detection with Vision Transformers](https://arxiv.org/abs/2205.06230) by Matthias Minderer, Alexey Gritsenko, Austin Stone, Maxim Neumann, Dirk Weissenborn, Alexey Dosovitskiy, Aravindh Mahendran, Anurag Arnab, Mostafa Dehghani, Zhuoran Shen, Xiao Wang, Xiaohua Zhai, Thomas Kipf, and Neil Houlsby. OWL-ViT is an open-vocabulary object detection network trained on a variety of (image, text) pairs. It can be used to query an image with one or multiple text queries to search for and detect target objects described in text.
+
+The abstract from the paper is the following:
+
+*Combining simple architectures with large-scale pre-training has led to massive improvements in image classification. For object detection, pre-training and scaling approaches are less well established, especially in the long-tailed and open-vocabulary setting, where training data is relatively scarce. In this paper, we propose a strong recipe for transferring image-text models to open-vocabulary object detection. We use a standard Vision Transformer architecture with minimal modifications, contrastive image-text pre-training, and end-to-end detection fine-tuning. Our analysis of the scaling properties of this setup shows that increasing image-level pre-training and model size yield consistent improvements on the downstream detection task. We provide the adaptation strategies and regularizations needed to attain very strong performance on zero-shot text-conditioned and one-shot image-conditioned object detection. Code and models are available on GitHub.*
+
+
+
+ OWL-ViT architecture. Taken from the original paper.
+
+This model was contributed by [adirik](https://huggingface.co/adirik). The original code can be found [here](https://github.com/google-research/scenic/tree/main/scenic/projects/owl_vit).
+
+## Usage tips
+
+OWL-ViT is a zero-shot text-conditioned object detection model. OWL-ViT uses [CLIP](clip) as its multi-modal backbone, with a ViT-like Transformer to get visual features and a causal language model to get the text features. To use CLIP for detection, OWL-ViT removes the final token pooling layer of the vision model and attaches a lightweight classification and box head to each transformer output token. Open-vocabulary classification is enabled by replacing the fixed classification layer weights with the class-name embeddings obtained from the text model. The authors first train CLIP from scratch and fine-tune it end-to-end with the classification and box heads on standard detection datasets using a bipartite matching loss. One or multiple text queries per image can be used to perform zero-shot text-conditioned object detection.
+
+[`OwlViTImageProcessor`] can be used to resize (or rescale) and normalize images for the model and [`CLIPTokenizer`] is used to encode the text. [`OwlViTProcessor`] wraps [`OwlViTImageProcessor`] and [`CLIPTokenizer`] into a single instance to both encode the text and prepare the images. The following example shows how to perform object detection using [`OwlViTProcessor`] and [`OwlViTForObjectDetection`].
+
+```python
+>>> import requests
+>>> from PIL import Image
+>>> import torch
+
+>>> from transformers import OwlViTProcessor, OwlViTForObjectDetection
+
+>>> processor = OwlViTProcessor.from_pretrained("google/owlvit-base-patch32")
+>>> model = OwlViTForObjectDetection.from_pretrained("google/owlvit-base-patch32")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> texts = [["a photo of a cat", "a photo of a dog"]]
+>>> inputs = processor(text=texts, images=image, return_tensors="pt")
+>>> outputs = model(**inputs)
+
+>>> # Target image sizes (height, width) to rescale box predictions [batch_size, 2]
+>>> target_sizes = torch.Tensor([image.size[::-1]])
+>>> # Convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax)
+>>> results = processor.post_process_object_detection(outputs=outputs, target_sizes=target_sizes, threshold=0.1)
+>>> i = 0 # Retrieve predictions for the first image for the corresponding text queries
+>>> text = texts[i]
+>>> boxes, scores, labels = results[i]["boxes"], results[i]["scores"], results[i]["labels"]
+>>> for box, score, label in zip(boxes, scores, labels):
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"Detected {text[label]} with confidence {round(score.item(), 3)} at location {box}")
+Detected a photo of a cat with confidence 0.707 at location [324.97, 20.44, 640.58, 373.29]
+Detected a photo of a cat with confidence 0.717 at location [1.46, 55.26, 315.55, 472.17]
+```
+
+## Resources
+
+A demo notebook on using OWL-ViT for zero- and one-shot (image-guided) object detection can be found [here](https://github.com/huggingface/notebooks/blob/main/examples/zeroshot_object_detection_with_owlvit.ipynb).
+
+## OwlViTConfig
+
+[[autodoc]] OwlViTConfig
+ - from_text_vision_configs
+
+## OwlViTTextConfig
+
+[[autodoc]] OwlViTTextConfig
+
+## OwlViTVisionConfig
+
+[[autodoc]] OwlViTVisionConfig
+
+## OwlViTImageProcessor
+
+[[autodoc]] OwlViTImageProcessor
+ - preprocess
+ - post_process_object_detection
+ - post_process_image_guided_detection
+
+## OwlViTFeatureExtractor
+
+[[autodoc]] OwlViTFeatureExtractor
+ - __call__
+ - post_process
+ - post_process_image_guided_detection
+
+## OwlViTProcessor
+
+[[autodoc]] OwlViTProcessor
+
+## OwlViTModel
+
+[[autodoc]] OwlViTModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## OwlViTTextModel
+
+[[autodoc]] OwlViTTextModel
+ - forward
+
+## OwlViTVisionModel
+
+[[autodoc]] OwlViTVisionModel
+ - forward
+
+## OwlViTForObjectDetection
+
+[[autodoc]] OwlViTForObjectDetection
+ - forward
+ - image_guided_detection
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/paligemma.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/paligemma.md
new file mode 100644
index 0000000000000000000000000000000000000000..8b88db39bd71650ae2283d8e60d2c261d10d4b39
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/paligemma.md
@@ -0,0 +1,106 @@
+
+
+# PaliGemma
+
+## Overview
+
+The PaliGemma model was proposed in [PaliGemma – Google's Cutting-Edge Open Vision Language Model](https://huggingface.co/blog/paligemma) by Google. It is a 3B vision-language model composed by a [SigLIP](siglip) vision encoder and a [Gemma](gemma) language decoder linked by a multimodal linear projection. It cuts an image into a fixed number of VIT tokens and prepends it to an optional prompt. One particularity is that the model uses full block attention on all the image tokens plus the input text tokens. It comes in 3 resolutions, 224x224, 448x448 and 896x896 with 3 base models, with 55 fine-tuned versions for different tasks, and 2 mix models.
+
+
+
+ PaliGemma architecture. Taken from the blog post.
+
+This model was contributed by [Molbap](https://huggingface.co/Molbap).
+
+## Usage tips
+
+- PaliGemma is not meant for conversational use, and it works best when fine-tuning to a specific use case. Some downstream tasks on which PaliGemma can be fine-tuned include image captioning, visual question answering (VQA), object detection, referring expression segmentation and document understanding.
+- One can use `PaliGemmaProcessor` to prepare images, text and optional labels for the model. When fine-tuning a PaliGemma model, the `suffix` argument can be passed to the processor which creates the `labels` for the model:
+
+```python
+prompt = "What is on the flower?"
+answer = "a bee"
+inputs = processor(images=raw_image, text=prompt, suffix=answer, return_tensors="pt")
+```
+
+## Usage Example
+
+The model can accept a single or multiple images. According to the [paper](https://arxiv.org/abs/2407.07726v1), the checkpoint PaliGemma can transfer to tasks which take multiple images as input. NLVR2 is one such task, which asks one question about two images, and requires looking at both to give the correct answer. Here's an example code for single and multi image inference.
+
+### Single-image Inference
+
+```python
+from transformers import AutoProcessor, PaliGemmaForConditionalGeneration
+
+model_id = "google/paligemma-3b-mix-224"
+model = PaliGemmaForConditionalGeneration.from_pretrained(model_id)
+processor = AutoProcessor.from_pretrained(model_id)
+
+prompt = "What is on the flower?"
+image_file = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg?download=true"
+raw_image = Image.open(requests.get(image_file, stream=True).raw)
+inputs = processor(raw_image, prompt, return_tensors="pt")
+output = model.generate(**inputs, max_new_tokens=20)
+
+print(processor.decode(output[0], skip_special_tokens=True)[inputs.input_ids.shape[1]: ])
+```
+
+### Multi-image Inference
+
+```python
+model_id = "google/paligemma-3b-ft-nlvr2-448" # checkpoint tuned for multiple images
+model = PaliGemmaForConditionalGeneration.from_pretrained(model_id)
+processor = PaliGemmaProcessor.from_pretrained(model_id)
+
+prompt = "answer en Which of the two pictures shows a snowman, first or second?"
+stop_sign_image = Image.open(
+ requests.get("https://www.ilankelman.org/stopsigns/australia.jpg", stream=True).raw
+)
+snow_image = Image.open(
+ requests.get(
+ "https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/snowman.jpg", stream=True
+ ).raw
+)
+
+inputs = processor(images=[[snow_image, stop_sign_image]], text=prompt, return_tensors="pt")
+
+output = model.generate(**inputs, max_new_tokens=20)
+print(processor.decode(output[0], skip_special_tokens=True)[inputs.input_ids.shape[1]: ])
+
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with PaliGemma. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- A blog post introducing all the features of PaliGemma can be found [here](https://huggingface.co/blog/paligemma).
+- Demo notebooks on how to fine-tune PaliGemma for VQA with the Trainer API along with inference can be found [here](https://github.com/huggingface/notebooks/tree/main/examples/paligemma).
+- Demo notebooks on how to fine-tune PaliGemma on a custom dataset (receipt image -> JSON) along with inference can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/PaliGemma). 🌎
+
+## PaliGemmaConfig
+
+[[autodoc]] PaliGemmaConfig
+
+## PaliGemmaProcessor
+
+[[autodoc]] PaliGemmaProcessor
+
+## PaliGemmaForConditionalGeneration
+
+[[autodoc]] PaliGemmaForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/patchtsmixer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/patchtsmixer.md
new file mode 100644
index 0000000000000000000000000000000000000000..a67138e533b71ad53ad4bfef4537b72da11bb91c
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/patchtsmixer.md
@@ -0,0 +1,94 @@
+
+
+# PatchTSMixer
+
+## Overview
+
+The PatchTSMixer model was proposed in [TSMixer: Lightweight MLP-Mixer Model for Multivariate Time Series Forecasting](https://arxiv.org/pdf/2306.09364.pdf) by Vijay Ekambaram, Arindam Jati, Nam Nguyen, Phanwadee Sinthong and Jayant Kalagnanam.
+
+
+PatchTSMixer is a lightweight time-series modeling approach based on the MLP-Mixer architecture. In this HuggingFace implementation, we provide PatchTSMixer's capabilities to effortlessly facilitate lightweight mixing across patches, channels, and hidden features for effective multivariate time-series modeling. It also supports various attention mechanisms starting from simple gated attention to more complex self-attention blocks that can be customized accordingly. The model can be pretrained and subsequently used for various downstream tasks such as forecasting, classification and regression.
+
+
+The abstract from the paper is the following:
+
+*TSMixer is a lightweight neural architecture exclusively composed of multi-layer perceptron (MLP) modules designed for multivariate forecasting and representation learning on patched time series. Our model draws inspiration from the success of MLP-Mixer models in computer vision. We demonstrate the challenges involved in adapting Vision MLP-Mixer for time series and introduce empirically validated components to enhance accuracy. This includes a novel design paradigm of attaching online reconciliation heads to the MLP-Mixer backbone, for explicitly modeling the time-series properties such as hierarchy and channel-correlations. We also propose a Hybrid channel modeling approach to effectively handle noisy channel interactions and generalization across diverse datasets, a common challenge in existing patch channel-mixing methods. Additionally, a simple gated attention mechanism is introduced in the backbone to prioritize important features. By incorporating these lightweight components, we significantly enhance the learning capability of simple MLP structures, outperforming complex Transformer models with minimal computing usage. Moreover, TSMixer's modular design enables compatibility with both supervised and masked self-supervised learning methods, making it a promising building block for time-series Foundation Models. TSMixer outperforms state-of-the-art MLP and Transformer models in forecasting by a considerable margin of 8-60%. It also outperforms the latest strong benchmarks of Patch-Transformer models (by 1-2%) with a significant reduction in memory and runtime (2-3X).*
+
+This model was contributed by [ajati](https://huggingface.co/ajati), [vijaye12](https://huggingface.co/vijaye12),
+[gsinthong](https://huggingface.co/gsinthong), [namctin](https://huggingface.co/namctin),
+[wmgifford](https://huggingface.co/wmgifford), [kashif](https://huggingface.co/kashif).
+
+## Usage example
+
+The code snippet below shows how to randomly initialize a PatchTSMixer model. The model is compatible with the [Trainer API](../trainer.md).
+
+```python
+
+from transformers import PatchTSMixerConfig, PatchTSMixerForPrediction
+from transformers import Trainer, TrainingArguments,
+
+
+config = PatchTSMixerConfig(context_length = 512, prediction_length = 96)
+model = PatchTSMixerForPrediction(config)
+trainer = Trainer(model=model, args=training_args,
+ train_dataset=train_dataset,
+ eval_dataset=valid_dataset)
+trainer.train()
+results = trainer.evaluate(test_dataset)
+```
+
+## Usage tips
+
+The model can also be used for time series classification and time series regression. See the respective [`PatchTSMixerForTimeSeriesClassification`] and [`PatchTSMixerForRegression`] classes.
+
+## Resources
+
+- A blog post explaining PatchTSMixer in depth can be found [here](https://huggingface.co/blog/patchtsmixer). The blog can also be opened in Google Colab.
+
+## PatchTSMixerConfig
+
+[[autodoc]] PatchTSMixerConfig
+
+
+## PatchTSMixerModel
+
+[[autodoc]] PatchTSMixerModel
+ - forward
+
+
+## PatchTSMixerForPrediction
+
+[[autodoc]] PatchTSMixerForPrediction
+ - forward
+
+
+## PatchTSMixerForTimeSeriesClassification
+
+[[autodoc]] PatchTSMixerForTimeSeriesClassification
+ - forward
+
+
+## PatchTSMixerForPretraining
+
+[[autodoc]] PatchTSMixerForPretraining
+ - forward
+
+
+## PatchTSMixerForRegression
+
+[[autodoc]] PatchTSMixerForRegression
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/patchtst.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/patchtst.md
new file mode 100644
index 0000000000000000000000000000000000000000..544e4cb378c6df3297e2c46d98ace5c1c7be44a1
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/patchtst.md
@@ -0,0 +1,68 @@
+
+
+# PatchTST
+
+## Overview
+
+The PatchTST model was proposed in [A Time Series is Worth 64 Words: Long-term Forecasting with Transformers](https://arxiv.org/abs/2211.14730) by Yuqi Nie, Nam H. Nguyen, Phanwadee Sinthong and Jayant Kalagnanam.
+
+At a high level the model vectorizes time series into patches of a given size and encodes the resulting sequence of vectors via a Transformer that then outputs the prediction length forecast via an appropriate head. The model is illustrated in the following figure:
+
+
+
+The abstract from the paper is the following:
+
+*We propose an efficient design of Transformer-based models for multivariate time series forecasting and self-supervised representation learning. It is based on two key components: (i) segmentation of time series into subseries-level patches which are served as input tokens to Transformer; (ii) channel-independence where each channel contains a single univariate time series that shares the same embedding and Transformer weights across all the series. Patching design naturally has three-fold benefit: local semantic information is retained in the embedding; computation and memory usage of the attention maps are quadratically reduced given the same look-back window; and the model can attend longer history. Our channel-independent patch time series Transformer (PatchTST) can improve the long-term forecasting accuracy significantly when compared with that of SOTA Transformer-based models. We also apply our model to self-supervised pre-training tasks and attain excellent fine-tuning performance, which outperforms supervised training on large datasets. Transferring of masked pre-trained representation on one dataset to others also produces SOTA forecasting accuracy.*
+
+This model was contributed by [namctin](https://huggingface.co/namctin), [gsinthong](https://huggingface.co/gsinthong), [diepi](https://huggingface.co/diepi), [vijaye12](https://huggingface.co/vijaye12), [wmgifford](https://huggingface.co/wmgifford), and [kashif](https://huggingface.co/kashif). The original code can be found [here](https://github.com/yuqinie98/PatchTST).
+
+## Usage tips
+
+The model can also be used for time series classification and time series regression. See the respective [`PatchTSTForClassification`] and [`PatchTSTForRegression`] classes.
+
+## Resources
+
+- A blog post explaining PatchTST in depth can be found [here](https://huggingface.co/blog/patchtst). The blog can also be opened in Google Colab.
+
+## PatchTSTConfig
+
+[[autodoc]] PatchTSTConfig
+
+## PatchTSTModel
+
+[[autodoc]] PatchTSTModel
+ - forward
+
+## PatchTSTForPrediction
+
+[[autodoc]] PatchTSTForPrediction
+ - forward
+
+## PatchTSTForClassification
+
+[[autodoc]] PatchTSTForClassification
+ - forward
+
+## PatchTSTForPretraining
+
+[[autodoc]] PatchTSTForPretraining
+ - forward
+
+## PatchTSTForRegression
+
+[[autodoc]] PatchTSTForRegression
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pegasus.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pegasus.md
new file mode 100644
index 0000000000000000000000000000000000000000..0622354e62dedfb156856da8af3a92a5508ae0db
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pegasus.md
@@ -0,0 +1,171 @@
+
+
+# Pegasus
+
+
+
+
+## Overview
+
+The Pegasus model was proposed in [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/pdf/1912.08777.pdf) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu on Dec 18, 2019.
+
+According to the abstract,
+
+- Pegasus' pretraining task is intentionally similar to summarization: important sentences are removed/masked from an
+ input document and are generated together as one output sequence from the remaining sentences, similar to an
+ extractive summary.
+- Pegasus achieves SOTA summarization performance on all 12 downstream tasks, as measured by ROUGE and human eval.
+
+This model was contributed by [sshleifer](https://huggingface.co/sshleifer). The Authors' code can be found [here](https://github.com/google-research/pegasus).
+
+## Usage tips
+
+- Sequence-to-sequence model with the same encoder-decoder model architecture as BART. Pegasus is pre-trained jointly on two self-supervised objective functions: Masked Language Modeling (MLM) and a novel summarization specific pretraining objective, called Gap Sentence Generation (GSG).
+
+ * MLM: encoder input tokens are randomly replaced by a mask tokens and have to be predicted by the encoder (like in BERT)
+ * GSG: whole encoder input sentences are replaced by a second mask token and fed to the decoder, but which has a causal mask to hide the future words like a regular auto-regressive transformer decoder.
+
+- FP16 is not supported (help/ideas on this appreciated!).
+- The adafactor optimizer is recommended for pegasus fine-tuning.
+
+
+## Checkpoints
+
+All the [checkpoints](https://huggingface.co/models?search=pegasus) are fine-tuned for summarization, besides
+*pegasus-large*, whence the other checkpoints are fine-tuned:
+
+- Each checkpoint is 2.2 GB on disk and 568M parameters.
+- FP16 is not supported (help/ideas on this appreciated!).
+- Summarizing xsum in fp32 takes about 400ms/sample, with default parameters on a v100 GPU.
+- Full replication results and correctly pre-processed data can be found in this [Issue](https://github.com/huggingface/transformers/issues/6844#issue-689259666).
+- [Distilled checkpoints](https://huggingface.co/models?search=distill-pegasus) are described in this [paper](https://arxiv.org/abs/2010.13002).
+
+## Implementation Notes
+
+- All models are transformer encoder-decoders with 16 layers in each component.
+- The implementation is completely inherited from [`BartForConditionalGeneration`]
+- Some key configuration differences:
+ - static, sinusoidal position embeddings
+ - the model starts generating with pad_token_id (which has 0 token_embedding) as the prefix.
+ - more beams are used (`num_beams=8`)
+- All pretrained pegasus checkpoints are the same besides three attributes: `tokenizer.model_max_length` (maximum
+ input size), `max_length` (the maximum number of tokens to generate) and `length_penalty`.
+- The code to convert checkpoints trained in the author's [repo](https://github.com/google-research/pegasus) can be
+ found in `convert_pegasus_tf_to_pytorch.py`.
+
+## Usage Example
+
+```python
+>>> from transformers import PegasusForConditionalGeneration, PegasusTokenizer
+>>> import torch
+
+>>> src_text = [
+... """ PG&E stated it scheduled the blackouts in response to forecasts for high winds amid dry conditions. The aim is to reduce the risk of wildfires. Nearly 800 thousand customers were scheduled to be affected by the shutoffs which were expected to last through at least midday tomorrow."""
+... ]
+
+... model_name = "google/pegasus-xsum"
+... device = "cuda" if torch.cuda.is_available() else "cpu"
+... tokenizer = PegasusTokenizer.from_pretrained(model_name)
+... model = PegasusForConditionalGeneration.from_pretrained(model_name).to(device)
+... batch = tokenizer(src_text, truncation=True, padding="longest", return_tensors="pt").to(device)
+... translated = model.generate(**batch)
+... tgt_text = tokenizer.batch_decode(translated, skip_special_tokens=True)
+... assert (
+... tgt_text[0]
+... == "California's largest electricity provider has turned off power to hundreds of thousands of customers."
+... )
+```
+
+## Resources
+
+- [Script](https://github.com/huggingface/transformers/tree/main/examples/research_projects/seq2seq-distillation/finetune_pegasus_xsum.sh) to fine-tune pegasus
+ on the XSUM dataset. Data download instructions at [examples/pytorch/summarization/](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization/README.md).
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## PegasusConfig
+
+[[autodoc]] PegasusConfig
+
+## PegasusTokenizer
+
+warning: `add_tokens` does not work at the moment.
+
+[[autodoc]] PegasusTokenizer
+
+## PegasusTokenizerFast
+
+[[autodoc]] PegasusTokenizerFast
+
+
+
+
+## PegasusModel
+
+[[autodoc]] PegasusModel
+ - forward
+
+## PegasusForConditionalGeneration
+
+[[autodoc]] PegasusForConditionalGeneration
+ - forward
+
+## PegasusForCausalLM
+
+[[autodoc]] PegasusForCausalLM
+ - forward
+
+
+
+
+## TFPegasusModel
+
+[[autodoc]] TFPegasusModel
+ - call
+
+## TFPegasusForConditionalGeneration
+
+[[autodoc]] TFPegasusForConditionalGeneration
+ - call
+
+
+
+
+## FlaxPegasusModel
+
+[[autodoc]] FlaxPegasusModel
+ - __call__
+ - encode
+ - decode
+
+## FlaxPegasusForConditionalGeneration
+
+[[autodoc]] FlaxPegasusForConditionalGeneration
+ - __call__
+ - encode
+ - decode
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pegasus_x.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pegasus_x.md
new file mode 100644
index 0000000000000000000000000000000000000000..d64d8ba954163e723a7cb30f7b533a86406beed5
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pegasus_x.md
@@ -0,0 +1,54 @@
+
+
+# PEGASUS-X
+
+## Overview
+
+The PEGASUS-X model was proposed in [Investigating Efficiently Extending Transformers for Long Input Summarization](https://arxiv.org/abs/2208.04347) by Jason Phang, Yao Zhao and Peter J. Liu.
+
+PEGASUS-X (PEGASUS eXtended) extends the PEGASUS models for long input summarization through additional long input pretraining and using staggered block-local attention with global tokens in the encoder.
+
+The abstract from the paper is the following:
+
+*While large pretrained Transformer models have proven highly capable at tackling natural language tasks, handling long sequence inputs continues to be a significant challenge. One such task is long input summarization, where inputs are longer than the maximum input context of most pretrained models. Through an extensive set of experiments, we investigate what model architectural changes and pretraining paradigms can most efficiently adapt a pretrained Transformer for long input summarization. We find that a staggered, block-local Transformer with global encoder tokens strikes a good balance of performance and efficiency, and that an additional pretraining phase on long sequences meaningfully improves downstream summarization performance. Based on our findings, we introduce PEGASUS-X, an extension of the PEGASUS model with additional long input pretraining to handle inputs of up to 16K tokens. PEGASUS-X achieves strong performance on long input summarization tasks comparable with much larger models while adding few additional parameters and not requiring model parallelism to train.*
+
+This model was contributed by [zphang](https://huggingface.co/zphang). The original code can be found [here](https://github.com/google-research/pegasus).
+
+## Documentation resources
+
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+
+
+PEGASUS-X uses the same tokenizer as [PEGASUS](pegasus).
+
+
+
+## PegasusXConfig
+
+[[autodoc]] PegasusXConfig
+
+## PegasusXModel
+
+[[autodoc]] PegasusXModel
+ - forward
+
+## PegasusXForConditionalGeneration
+
+[[autodoc]] PegasusXForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/perceiver.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/perceiver.md
new file mode 100644
index 0000000000000000000000000000000000000000..ee678c22f6f8900f045a700ac382550c95772e85
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/perceiver.md
@@ -0,0 +1,229 @@
+
+
+# Perceiver
+
+## Overview
+
+The Perceiver IO model was proposed in [Perceiver IO: A General Architecture for Structured Inputs &
+Outputs](https://arxiv.org/abs/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch,
+Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M.
+Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
+
+Perceiver IO is a generalization of [Perceiver](https://arxiv.org/abs/2103.03206) to handle arbitrary outputs in
+addition to arbitrary inputs. The original Perceiver only produced a single classification label. In addition to
+classification labels, Perceiver IO can produce (for example) language, optical flow, and multimodal videos with audio.
+This is done using the same building blocks as the original Perceiver. The computational complexity of Perceiver IO is
+linear in the input and output size and the bulk of the processing occurs in the latent space, allowing us to process
+inputs and outputs that are much larger than can be handled by standard Transformers. This means, for example,
+Perceiver IO can do BERT-style masked language modeling directly using bytes instead of tokenized inputs.
+
+The abstract from the paper is the following:
+
+*The recently-proposed Perceiver model obtains good results on several domains (images, audio, multimodal, point
+clouds) while scaling linearly in compute and memory with the input size. While the Perceiver supports many kinds of
+inputs, it can only produce very simple outputs such as class scores. Perceiver IO overcomes this limitation without
+sacrificing the original's appealing properties by learning to flexibly query the model's latent space to produce
+outputs of arbitrary size and semantics. Perceiver IO still decouples model depth from data size and still scales
+linearly with data size, but now with respect to both input and output sizes. The full Perceiver IO model achieves
+strong results on tasks with highly structured output spaces, such as natural language and visual understanding,
+StarCraft II, and multi-task and multi-modal domains. As highlights, Perceiver IO matches a Transformer-based BERT
+baseline on the GLUE language benchmark without the need for input tokenization and achieves state-of-the-art
+performance on Sintel optical flow estimation.*
+
+Here's a TLDR explaining how Perceiver works:
+
+The main problem with the self-attention mechanism of the Transformer is that the time and memory requirements scale
+quadratically with the sequence length. Hence, models like BERT and RoBERTa are limited to a max sequence length of 512
+tokens. Perceiver aims to solve this issue by, instead of performing self-attention on the inputs, perform it on a set
+of latent variables, and only use the inputs for cross-attention. In this way, the time and memory requirements don't
+depend on the length of the inputs anymore, as one uses a fixed amount of latent variables, like 256 or 512. These are
+randomly initialized, after which they are trained end-to-end using backpropagation.
+
+Internally, [`PerceiverModel`] will create the latents, which is a tensor of shape `(batch_size, num_latents,
+d_latents)`. One must provide `inputs` (which could be text, images, audio, you name it!) to the model, which it will
+use to perform cross-attention with the latents. The output of the Perceiver encoder is a tensor of the same shape. One
+can then, similar to BERT, convert the last hidden states of the latents to classification logits by averaging along
+the sequence dimension, and placing a linear layer on top of that to project the `d_latents` to `num_labels`.
+
+This was the idea of the original Perceiver paper. However, it could only output classification logits. In a follow-up
+work, PerceiverIO, they generalized it to let the model also produce outputs of arbitrary size. How, you might ask? The
+idea is actually relatively simple: one defines outputs of an arbitrary size, and then applies cross-attention with the
+last hidden states of the latents, using the outputs as queries, and the latents as keys and values.
+
+So let's say one wants to perform masked language modeling (BERT-style) with the Perceiver. As the Perceiver's input
+length will not have an impact on the computation time of the self-attention layers, one can provide raw bytes,
+providing `inputs` of length 2048 to the model. If one now masks out certain of these 2048 tokens, one can define the
+`outputs` as being of shape: `(batch_size, 2048, 768)`. Next, one performs cross-attention with the final hidden states
+of the latents to update the `outputs` tensor. After cross-attention, one still has a tensor of shape `(batch_size,
+2048, 768)`. One can then place a regular language modeling head on top, to project the last dimension to the
+vocabulary size of the model, i.e. creating logits of shape `(batch_size, 2048, 262)` (as Perceiver uses a vocabulary
+size of 262 byte IDs).
+
+
+
+ Perceiver IO architecture. Taken from the original paper
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found
+[here](https://github.com/deepmind/deepmind-research/tree/master/perceiver).
+
+
+
+Perceiver does **not** work with `torch.nn.DataParallel` due to a bug in PyTorch, see [issue #36035](https://github.com/pytorch/pytorch/issues/36035)
+
+
+
+## Resources
+
+- The quickest way to get started with the Perceiver is by checking the [tutorial
+ notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Perceiver).
+- Refer to the [blog post](https://huggingface.co/blog/perceiver) if you want to fully understand how the model works and
+is implemented in the library. Note that the models available in the library only showcase some examples of what you can do
+with the Perceiver. There are many more use cases, including question answering, named-entity recognition, object detection,
+audio classification, video classification, etc.
+- [Text classification task guide](../tasks/sequence_classification)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Image classification task guide](../tasks/image_classification)
+
+## Perceiver specific outputs
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverModelOutput
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverDecoderOutput
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverMaskedLMOutput
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverClassifierOutput
+
+## PerceiverConfig
+
+[[autodoc]] PerceiverConfig
+
+## PerceiverTokenizer
+
+[[autodoc]] PerceiverTokenizer
+ - __call__
+
+## PerceiverFeatureExtractor
+
+[[autodoc]] PerceiverFeatureExtractor
+ - __call__
+
+## PerceiverImageProcessor
+
+[[autodoc]] PerceiverImageProcessor
+ - preprocess
+
+## PerceiverTextPreprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverTextPreprocessor
+
+## PerceiverImagePreprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverImagePreprocessor
+
+## PerceiverOneHotPreprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverOneHotPreprocessor
+
+## PerceiverAudioPreprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverAudioPreprocessor
+
+## PerceiverMultimodalPreprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverMultimodalPreprocessor
+
+## PerceiverProjectionDecoder
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverProjectionDecoder
+
+## PerceiverBasicDecoder
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverBasicDecoder
+
+## PerceiverClassificationDecoder
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverClassificationDecoder
+
+## PerceiverOpticalFlowDecoder
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverOpticalFlowDecoder
+
+## PerceiverBasicVideoAutoencodingDecoder
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverBasicVideoAutoencodingDecoder
+
+## PerceiverMultimodalDecoder
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverMultimodalDecoder
+
+## PerceiverProjectionPostprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverProjectionPostprocessor
+
+## PerceiverAudioPostprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverAudioPostprocessor
+
+## PerceiverClassificationPostprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverClassificationPostprocessor
+
+## PerceiverMultimodalPostprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverMultimodalPostprocessor
+
+## PerceiverModel
+
+[[autodoc]] PerceiverModel
+ - forward
+
+## PerceiverForMaskedLM
+
+[[autodoc]] PerceiverForMaskedLM
+ - forward
+
+## PerceiverForSequenceClassification
+
+[[autodoc]] PerceiverForSequenceClassification
+ - forward
+
+## PerceiverForImageClassificationLearned
+
+[[autodoc]] PerceiverForImageClassificationLearned
+ - forward
+
+## PerceiverForImageClassificationFourier
+
+[[autodoc]] PerceiverForImageClassificationFourier
+ - forward
+
+## PerceiverForImageClassificationConvProcessing
+
+[[autodoc]] PerceiverForImageClassificationConvProcessing
+ - forward
+
+## PerceiverForOpticalFlow
+
+[[autodoc]] PerceiverForOpticalFlow
+ - forward
+
+## PerceiverForMultimodalAutoencoding
+
+[[autodoc]] PerceiverForMultimodalAutoencoding
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/persimmon.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/persimmon.md
new file mode 100644
index 0000000000000000000000000000000000000000..7a105ac5543d60cc18f4ecce329fd03c2e0a3f9b
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/persimmon.md
@@ -0,0 +1,103 @@
+
+
+# Persimmon
+
+## Overview
+
+The Persimmon model was created by [ADEPT](https://www.adept.ai/blog/persimmon-8b), and authored by Erich Elsen, Augustus Odena, Maxwell Nye, Sağnak Taşırlar, Tri Dao, Curtis Hawthorne, Deepak Moparthi, Arushi Somani.
+
+The authors introduced Persimmon-8B, a decoder model based on the classic transformers architecture, with query and key normalization. Persimmon-8B is a fully permissively-licensed model with approximately 8 billion parameters, released under the Apache license. Some of the key attributes of Persimmon-8B are long context size (16K), performance, and capabilities for multimodal extensions.
+
+The authors showcase their approach to model evaluation, focusing on practical text generation, mirroring how users interact with language models. The work also includes a comparative analysis, pitting Persimmon-8B against other prominent models (MPT 7B Instruct and Llama 2 Base 7B 1-Shot), across various evaluation tasks. The results demonstrate Persimmon-8B's competitive performance, even with limited training data.
+
+In terms of model details, the work outlines the architecture and training methodology of Persimmon-8B, providing insights into its design choices, sequence length, and dataset composition. The authors present a fast inference code that outperforms traditional implementations through operator fusion and CUDA graph utilization while maintaining code coherence. They express their anticipation of how the community will leverage this contribution to drive innovation, hinting at further upcoming releases as part of an ongoing series of developments.
+
+This model was contributed by [ArthurZ](https://huggingface.co/ArthurZ).
+The original code can be found [here](https://github.com/persimmon-ai-labs/adept-inference).
+
+## Usage tips
+
+
+
+The `Persimmon` models were trained using `bfloat16`, but the original inference uses `float16` The checkpoints uploaded on the hub use `torch_dtype = 'float16'` which will be
+used by the `AutoModel` API to cast the checkpoints from `torch.float32` to `torch.float16`.
+
+The `dtype` of the online weights is mostly irrelevant, unless you are using `torch_dtype="auto"` when initializing a model using `model = AutoModelForCausalLM.from_pretrained("path", torch_dtype = "auto")`. The reason is that the model will first be downloaded ( using the `dtype` of the checkpoints online) then it will be cast to the default `dtype` of `torch` (becomes `torch.float32`). Users should specify the `torch_dtype` they want, and if they don't it will be `torch.float32`.
+
+Finetuning the model in `float16` is not recommended and known to produce `nan`, as such the model should be fine-tuned in `bfloat16`.
+
+
+
+
+Tips:
+
+- To convert the model, you need to clone the original repository using `git clone https://github.com/persimmon-ai-labs/adept-inference`, then get the checkpoints:
+
+```bash
+git clone https://github.com/persimmon-ai-labs/adept-inference
+wget https://axtkn4xl5cip.objectstorage.us-phoenix-1.oci.customer-oci.com/n/axtkn4xl5cip/b/adept-public-data/o/8b_base_model_release.tar
+tar -xvf 8b_base_model_release.tar
+python src/transformers/models/persimmon/convert_persimmon_weights_to_hf.py --input_dir /path/to/downloaded/persimmon/weights/ --output_dir /output/path \
+ --pt_model_path /path/to/8b_chat_model_release/iter_0001251/mp_rank_00/model_optim_rng.pt
+ --ada_lib_path /path/to/adept-inference
+```
+
+For the chat model:
+```bash
+wget https://axtkn4xl5cip.objectstorage.us-phoenix-1.oci.customer-oci.com/n/axtkn4xl5cip/b/adept-public-data/o/8b_chat_model_release.tar
+tar -xvf 8b_base_model_release.tar
+```
+
+Thereafter, models can be loaded via:
+
+```py
+from transformers import PersimmonForCausalLM, PersimmonTokenizer
+
+model = PersimmonForCausalLM.from_pretrained("/output/path")
+tokenizer = PersimmonTokenizer.from_pretrained("/output/path")
+```
+
+
+- Perismmon uses a `sentencepiece` based tokenizer, with a `Unigram` model. It supports bytefallback, which is only available in `tokenizers==0.14.0` for the fast tokenizer.
+The `LlamaTokenizer` is used as it is a standard wrapper around sentencepiece. The `chat` template will be updated with the templating functions in a follow up PR!
+
+- The authors suggest to use the following prompt format for the chat mode: `f"human: {prompt}\n\nadept:"`
+
+
+## PersimmonConfig
+
+[[autodoc]] PersimmonConfig
+
+## PersimmonModel
+
+[[autodoc]] PersimmonModel
+ - forward
+
+## PersimmonForCausalLM
+
+[[autodoc]] PersimmonForCausalLM
+ - forward
+
+## PersimmonForSequenceClassification
+
+[[autodoc]] PersimmonForSequenceClassification
+ - forward
+
+## PersimmonForTokenClassification
+
+[[autodoc]] PersimmonForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/phi.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/phi.md
new file mode 100644
index 0000000000000000000000000000000000000000..ef163213bf141569d4a679dbfc67886dc1d5be7d
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/phi.md
@@ -0,0 +1,192 @@
+
+
+# Phi
+
+## Overview
+
+The Phi-1 model was proposed in [Textbooks Are All You Need](https://arxiv.org/abs/2306.11644) by Suriya Gunasekar, Yi Zhang, Jyoti Aneja, Caio César Teodoro Mendes, Allie Del Giorno, Sivakanth Gopi, Mojan Javaheripi, Piero Kauffmann, Gustavo de Rosa, Olli Saarikivi, Adil Salim, Shital Shah, Harkirat Singh Behl, Xin Wang, Sébastien Bubeck, Ronen Eldan, Adam Tauman Kalai, Yin Tat Lee and Yuanzhi Li.
+
+The Phi-1.5 model was proposed in [Textbooks Are All You Need II: phi-1.5 technical report](https://arxiv.org/abs/2309.05463) by Yuanzhi Li, Sébastien Bubeck, Ronen Eldan, Allie Del Giorno, Suriya Gunasekar and Yin Tat Lee.
+
+### Summary
+
+In Phi-1 and Phi-1.5 papers, the authors showed how important the quality of the data is in training relative to the model size.
+They selected high quality "textbook" data alongside with synthetically generated data for training their small sized Transformer
+based model Phi-1 with 1.3B parameters. Despite this small scale, phi-1 attains pass@1 accuracy 50.6% on HumanEval and 55.5% on MBPP.
+They follow the same strategy for Phi-1.5 and created another 1.3B parameter model with performance on natural language tasks comparable
+to models 5x larger, and surpassing most non-frontier LLMs. Phi-1.5 exhibits many of the traits of much larger LLMs such as the ability
+to “think step by step” or perform some rudimentary in-context learning.
+With these two experiments the authors successfully showed the huge impact of quality of training data when training machine learning models.
+
+The abstract from the Phi-1 paper is the following:
+
+*We introduce phi-1, a new large language model for code, with significantly smaller size than
+competing models: phi-1 is a Transformer-based model with 1.3B parameters, trained for 4 days on
+8 A100s, using a selection of “textbook quality” data from the web (6B tokens) and synthetically
+generated textbooks and exercises with GPT-3.5 (1B tokens). Despite this small scale, phi-1 attains
+pass@1 accuracy 50.6% on HumanEval and 55.5% on MBPP. It also displays surprising emergent
+properties compared to phi-1-base, our model before our finetuning stage on a dataset of coding
+exercises, and phi-1-small, a smaller model with 350M parameters trained with the same pipeline as
+phi-1 that still achieves 45% on HumanEval.*
+
+The abstract from the Phi-1.5 paper is the following:
+
+*We continue the investigation into the power of smaller Transformer-based language models as
+initiated by TinyStories – a 10 million parameter model that can produce coherent English – and
+the follow-up work on phi-1, a 1.3 billion parameter model with Python coding performance close
+to the state-of-the-art. The latter work proposed to use existing Large Language Models (LLMs) to
+generate “textbook quality” data as a way to enhance the learning process compared to traditional
+web data. We follow the “Textbooks Are All You Need” approach, focusing this time on common
+sense reasoning in natural language, and create a new 1.3 billion parameter model named phi-1.5,
+with performance on natural language tasks comparable to models 5x larger, and surpassing most
+non-frontier LLMs on more complex reasoning tasks such as grade-school mathematics and basic
+coding. More generally, phi-1.5 exhibits many of the traits of much larger LLMs, both good –such
+as the ability to “think step by step” or perform some rudimentary in-context learning– and bad,
+including hallucinations and the potential for toxic and biased generations –encouragingly though, we
+are seeing improvement on that front thanks to the absence of web data. We open-source phi-1.5 to
+promote further research on these urgent topics.*
+
+This model was contributed by [Susnato Dhar](https://huggingface.co/susnato).
+
+The original code for Phi-1, Phi-1.5 and Phi-2 can be found [here](https://huggingface.co/microsoft/phi-1), [here](https://huggingface.co/microsoft/phi-1_5) and [here](https://huggingface.co/microsoft/phi-2), respectively.
+
+## Usage tips
+
+- This model is quite similar to `Llama` with the main difference in [`PhiDecoderLayer`], where they used [`PhiAttention`] and [`PhiMLP`] layers in parallel configuration.
+- The tokenizer used for this model is identical to the [`CodeGenTokenizer`].
+
+## How to use Phi-2
+
+
+
+Phi-2 has been integrated in the development version (4.37.0.dev) of `transformers`. Until the official version is released through `pip`, ensure that you are doing one of the following:
+
+* When loading the model, ensure that `trust_remote_code=True` is passed as an argument of the `from_pretrained()` function.
+
+* Update your local `transformers` to the development version: `pip uninstall -y transformers && pip install git+https://github.com/huggingface/transformers`. The previous command is an alternative to cloning and installing from the source.
+
+
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("microsoft/phi-2")
+>>> tokenizer = AutoTokenizer.from_pretrained("microsoft/phi-2")
+
+>>> inputs = tokenizer('Can you help me write a formal email to a potential business partner proposing a joint venture?', return_tensors="pt", return_attention_mask=False)
+
+>>> outputs = model.generate(**inputs, max_length=30)
+>>> text = tokenizer.batch_decode(outputs)[0]
+>>> print(text)
+Can you help me write a formal email to a potential business partner proposing a joint venture?
+Input: Company A: ABC Inc.
+Company B
+```
+
+### Example :
+
+```python
+>>> from transformers import PhiForCausalLM, AutoTokenizer
+
+>>> # define the model and tokenizer.
+>>> model = PhiForCausalLM.from_pretrained("microsoft/phi-1_5")
+>>> tokenizer = AutoTokenizer.from_pretrained("microsoft/phi-1_5")
+
+>>> # feel free to change the prompt to your liking.
+>>> prompt = "If I were an AI that had just achieved"
+
+>>> # apply the tokenizer.
+>>> tokens = tokenizer(prompt, return_tensors="pt")
+
+>>> # use the model to generate new tokens.
+>>> generated_output = model.generate(**tokens, use_cache=True, max_new_tokens=10)
+
+>>> tokenizer.batch_decode(generated_output)[0]
+'If I were an AI that had just achieved a breakthrough in machine learning, I would be thrilled'
+```
+
+## Combining Phi and Flash Attention 2
+
+First, make sure to install the latest version of Flash Attention 2 to include the sliding window attention feature.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Make also sure that you have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of flash-attn repository. Make also sure to load your model in half-precision (e.g. `torch.float16``)
+
+To load and run a model using Flash Attention 2, refer to the snippet below:
+
+```python
+>>> import torch
+>>> from transformers import PhiForCausalLM, AutoTokenizer
+
+>>> # define the model and tokenizer and push the model and tokens to the GPU.
+>>> model = PhiForCausalLM.from_pretrained("microsoft/phi-1_5", torch_dtype=torch.float16, attn_implementation="flash_attention_2").to("cuda") # doctest: +SKIP
+>>> tokenizer = AutoTokenizer.from_pretrained("microsoft/phi-1_5")
+
+>>> # feel free to change the prompt to your liking.
+>>> prompt = "If I were an AI that had just achieved"
+
+>>> # apply the tokenizer.
+>>> tokens = tokenizer(prompt, return_tensors="pt").to("cuda")
+
+>>> # use the model to generate new tokens.
+>>> generated_output = model.generate(**tokens, use_cache=True, max_new_tokens=10) # doctest: +SKIP
+
+>>> tokenizer.batch_decode(generated_output)[0] # doctest: +SKIP
+'If I were an AI that had just achieved a breakthrough in machine learning, I would be thrilled'
+```
+
+### Expected speedups
+
+Below is an expected speedup diagram that compares pure inference time between the native implementation in transformers using `microsoft/phi-1` checkpoint and the Flash Attention 2 version of the model using a sequence length of 2048.
+
+
+
+
+
+## PhiConfig
+
+[[autodoc]] PhiConfig
+
+
+
+
+## PhiModel
+
+[[autodoc]] PhiModel
+ - forward
+
+## PhiForCausalLM
+
+[[autodoc]] PhiForCausalLM
+ - forward
+ - generate
+
+## PhiForSequenceClassification
+
+[[autodoc]] PhiForSequenceClassification
+ - forward
+
+## PhiForTokenClassification
+
+[[autodoc]] PhiForTokenClassification
+ - forward
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/phi3.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/phi3.md
new file mode 100644
index 0000000000000000000000000000000000000000..76d94008137eb27cba2d95ddc054a65d49795f4a
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/phi3.md
@@ -0,0 +1,95 @@
+
+
+# Phi-3
+
+## Overview
+
+The Phi-3 model was proposed in [Phi-3 Technical Report: A Highly Capable Language Model Locally on Your Phone](https://arxiv.org/abs/2404.14219) by Microsoft.
+
+### Summary
+
+The abstract from the Phi-3 paper is the following:
+
+We introduce phi-3-mini, a 3.8 billion parameter language model trained on 3.3 trillion tokens, whose overall performance, as measured by both academic benchmarks and internal testing, rivals that of models such as Mixtral 8x7B and GPT-3.5 (e.g., phi-3-mini achieves 69% on MMLU and 8.38 on MT-bench), despite being small enough to be deployed on a phone. The innovation lies entirely in our dataset for training, a scaled-up version of the one used for phi-2, composed of heavily filtered web data and synthetic data. The model is also further aligned for robustness, safety, and chat format. We also provide some initial parameter-scaling results with a 7B and 14B models trained for 4.8T tokens, called phi-3-small and phi-3-medium, both significantly more capable than phi-3-mini (e.g., respectively 75% and 78% on MMLU, and 8.7 and 8.9 on MT-bench).
+
+The original code for Phi-3 can be found [here](https://huggingface.co/microsoft/Phi-3-mini-4k-instruct).
+
+## Usage tips
+
+- This model is very similar to `Llama` with the main difference of [`Phi3SuScaledRotaryEmbedding`] and [`Phi3YarnScaledRotaryEmbedding`], where they are used to extend the context of the rotary embeddings. The query, key and values are fused, and the MLP's up and gate projection layers are also fused.
+- The tokenizer used for this model is identical to the [`LlamaTokenizer`], with the exception of additional tokens.
+
+## How to use Phi-3
+
+
+
+Phi-3 has been integrated in the development version (4.40.0.dev) of `transformers`. Until the official version is released through `pip`, ensure that you are doing one of the following:
+
+* When loading the model, ensure that `trust_remote_code=True` is passed as an argument of the `from_pretrained()` function.
+
+* Update your local `transformers` to the development version: `pip uninstall -y transformers && pip install git+https://github.com/huggingface/transformers`. The previous command is an alternative to cloning and installing from the source.
+
+
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("microsoft/Phi-3-mini-4k-instruct")
+>>> tokenizer = AutoTokenizer.from_pretrained("microsoft/Phi-3-mini-4k-instruct")
+
+>>> messages = [{"role": "user", "content": "Can you provide ways to eat combinations of bananas and dragonfruits?"}]
+>>> inputs = tokenizer.apply_chat_template(messages, add_generation_prompt=True, return_tensors="pt")
+
+>>> outputs = model.generate(inputs, max_new_tokens=32)
+>>> text = tokenizer.batch_decode(outputs)[0]
+>>> print(text)
+<|user|>
+Can you provide ways to eat combinations of bananas and dragonfruits?<|end|>
+<|assistant|>
+Certainly! Bananas and dragonfruits can be combined in various delicious ways. Here are some ideas for eating combinations of bananas and
+```
+
+## Phi3Config
+
+[[autodoc]] Phi3Config
+
+
+
+
+## Phi3Model
+
+[[autodoc]] Phi3Model
+ - forward
+
+## Phi3ForCausalLM
+
+[[autodoc]] Phi3ForCausalLM
+ - forward
+ - generate
+
+## Phi3ForSequenceClassification
+
+[[autodoc]] Phi3ForSequenceClassification
+ - forward
+
+## Phi3ForTokenClassification
+
+[[autodoc]] Phi3ForTokenClassification
+ - forward
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/phimoe.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/phimoe.md
new file mode 100644
index 0000000000000000000000000000000000000000..d9c9ae4a1831c77e025c296f321928702193838d
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/phimoe.md
@@ -0,0 +1,118 @@
+
+
+# PhiMoE
+
+## Overview
+
+The PhiMoE model was proposed in [Phi-3 Technical Report: A Highly Capable Language Model Locally on Your Phone](https://arxiv.org/abs/2404.14219) by Microsoft.
+
+### Summary
+
+The abstract from the Phi-3 paper is the following:
+
+We introduce phi-3-mini, a 3.8 billion parameter language model trained on 3.3 trillion tokens, whose overall performance, as measured by both academic benchmarks and internal testing, rivals that of models such as Mixtral 8x7B and GPT-3.5 (e.g., phi-3-mini achieves 69% on MMLU and 8.38 on MT-bench), despite being small enough to be deployed on a phone. Our training dataset is a scaled-up version of the one used for phi-2, composed of heavily filtered publicly available web data and synthetic data. The model is also further aligned for robustness, safety, and chat format. We also provide parameter-scaling results with a 7B, 14B models trained for 4.8T tokens, called phi-3-small, phi-3-medium, both significantly more capable than phi-3-mini (e.g., respectively 75%, 78% on MMLU, and 8.7, 8.9 on MT-bench). To enhance multilingual, multimodal, and long-context capabilities, we introduce three models in the phi-3.5 series: phi-3.5-mini, phi-3.5-MoE, and phi-3.5-Vision. The phi-3.5-MoE, a 16 x 3.8B MoE model with 6.6 billion active parameters, achieves superior performance in language reasoning, math, and code tasks compared to other open-source models of similar scale, such as Llama 3.1 and the Mixtral series, and on par with Gemini-1.5-Flash and GPT-4o-mini. Meanwhile, phi-3.5-Vision, a 4.2 billion parameter model derived from phi-3.5-mini, excels in reasoning tasks and is adept at handling both single-image and text prompts, as well as multi-image and text prompts.
+
+The original code for PhiMoE can be found [here](https://huggingface.co/microsoft/Phi-3.5-MoE-instruct).
+
+## Usage tips
+
+- This model is very similar to `Mixtral` with the main difference of [`Phi3LongRoPEScaledRotaryEmbedding`], where they are used to extend the context of the rotary embeddings. The query, key and values are fused, and the MLP's up and gate projection layers are also fused.
+- The tokenizer used for this model is identical to the [`LlamaTokenizer`], with the exception of additional tokens.
+
+## How to use PhiMoE
+
+
+
+Phi-3.5-MoE-instruct has been integrated in the development version (4.44.2.dev) of `transformers`. Until the official version is released through `pip`, ensure that you are doing the following:
+* When loading the model, ensure that `trust_remote_code=True` is passed as an argument of the `from_pretrained()` function.
+
+The current `transformers` version can be verified with: `pip list | grep transformers`.
+
+Examples of required packages:
+```
+flash_attn==2.5.8
+torch==2.3.1
+accelerate==0.31.0
+transformers==4.43.0
+```
+
+
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, pipeline
+
+torch.random.manual_seed(0)
+
+model = AutoModelForCausalLM.from_pretrained(
+ "microsoft/Phi-3.5-MoE-instruct",
+ device_map="cuda",
+ torch_dtype="auto",
+ trust_remote_code=True,
+)
+
+tokenizer = AutoTokenizer.from_pretrained("microsoft/Phi-3.5-MoE-instruct")
+
+messages = [
+ {"role": "system", "content": "You are a helpful AI assistant."},
+ {"role": "user", "content": "Can you provide ways to eat combinations of bananas and dragonfruits?"},
+ {"role": "assistant", "content": "Sure! Here are some ways to eat bananas and dragonfruits together: 1. Banana and dragonfruit smoothie: Blend bananas and dragonfruits together with some milk and honey. 2. Banana and dragonfruit salad: Mix sliced bananas and dragonfruits together with some lemon juice and honey."},
+ {"role": "user", "content": "What about solving an 2x + 3 = 7 equation?"},
+]
+
+pipe = pipeline(
+ "text-generation",
+ model=model,
+ tokenizer=tokenizer,
+)
+
+generation_args = {
+ "max_new_tokens": 500,
+ "return_full_text": False,
+ "temperature": 0.0,
+ "do_sample": False,
+}
+
+output = pipe(messages, **generation_args)
+print(output[0]['generated_text'])
+```
+
+## PhimoeConfig
+
+[[autodoc]] PhimoeConfig
+
+
+
+
+## PhimoeModel
+
+[[autodoc]] PhimoeModel
+ - forward
+
+## PhimoeForCausalLM
+
+[[autodoc]] PhimoeForCausalLM
+ - forward
+ - generate
+
+## PhimoeForSequenceClassification
+
+[[autodoc]] PhimoeForSequenceClassification
+ - forward
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/phobert.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/phobert.md
new file mode 100644
index 0000000000000000000000000000000000000000..adf5900ebe2a3e5470912086c0a7e0d6e3620cff
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/phobert.md
@@ -0,0 +1,64 @@
+
+
+# PhoBERT
+
+## Overview
+
+The PhoBERT model was proposed in [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92.pdf) by Dat Quoc Nguyen, Anh Tuan Nguyen.
+
+The abstract from the paper is the following:
+
+*We present PhoBERT with two versions, PhoBERT-base and PhoBERT-large, the first public large-scale monolingual
+language models pre-trained for Vietnamese. Experimental results show that PhoBERT consistently outperforms the recent
+best pre-trained multilingual model XLM-R (Conneau et al., 2020) and improves the state-of-the-art in multiple
+Vietnamese-specific NLP tasks including Part-of-speech tagging, Dependency parsing, Named-entity recognition and
+Natural language inference.*
+
+This model was contributed by [dqnguyen](https://huggingface.co/dqnguyen). The original code can be found [here](https://github.com/VinAIResearch/PhoBERT).
+
+## Usage example
+
+```python
+>>> import torch
+>>> from transformers import AutoModel, AutoTokenizer
+
+>>> phobert = AutoModel.from_pretrained("vinai/phobert-base")
+>>> tokenizer = AutoTokenizer.from_pretrained("vinai/phobert-base")
+
+>>> # INPUT TEXT MUST BE ALREADY WORD-SEGMENTED!
+>>> line = "Tôi là sinh_viên trường đại_học Công_nghệ ."
+
+>>> input_ids = torch.tensor([tokenizer.encode(line)])
+
+>>> with torch.no_grad():
+... features = phobert(input_ids) # Models outputs are now tuples
+
+>>> # With TensorFlow 2.0+:
+>>> # from transformers import TFAutoModel
+>>> # phobert = TFAutoModel.from_pretrained("vinai/phobert-base")
+```
+
+
+
+PhoBERT implementation is the same as BERT, except for tokenization. Refer to [BERT documentation](bert) for information on
+configuration classes and their parameters. PhoBERT-specific tokenizer is documented below.
+
+
+
+## PhobertTokenizer
+
+[[autodoc]] PhobertTokenizer
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pix2struct.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pix2struct.md
new file mode 100644
index 0000000000000000000000000000000000000000..0c9baa18e02fc825c35610b71e1f322ebb1f9063
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pix2struct.md
@@ -0,0 +1,77 @@
+
+
+# Pix2Struct
+
+## Overview
+
+The Pix2Struct model was proposed in [Pix2Struct: Screenshot Parsing as Pretraining for Visual Language Understanding](https://arxiv.org/abs/2210.03347) by Kenton Lee, Mandar Joshi, Iulia Turc, Hexiang Hu, Fangyu Liu, Julian Eisenschlos, Urvashi Khandelwal, Peter Shaw, Ming-Wei Chang, Kristina Toutanova.
+
+The abstract from the paper is the following:
+
+> Visually-situated language is ubiquitous -- sources range from textbooks with diagrams to web pages with images and tables, to mobile apps with buttons and forms. Perhaps due to this diversity, previous work has typically relied on domain-specific recipes with limited sharing of the underlying data, model architectures, and objectives. We present Pix2Struct, a pretrained image-to-text model for purely visual language understanding, which can be finetuned on tasks containing visually-situated language. Pix2Struct is pretrained by learning to parse masked screenshots of web pages into simplified HTML. The web, with its richness of visual elements cleanly reflected in the HTML structure, provides a large source of pretraining data well suited to the diversity of downstream tasks. Intuitively, this objective subsumes common pretraining signals such as OCR, language modeling, image captioning. In addition to the novel pretraining strategy, we introduce a variable-resolution input representation and a more flexible integration of language and vision inputs, where language prompts such as questions are rendered directly on top of the input image. For the first time, we show that a single pretrained model can achieve state-of-the-art results in six out of nine tasks across four domains: documents, illustrations, user interfaces, and natural images.
+
+Tips:
+
+Pix2Struct has been fine tuned on a variety of tasks and datasets, ranging from image captioning, visual question answering (VQA) over different inputs (books, charts, science diagrams), captioning UI components etc. The full list can be found in Table 1 of the paper.
+We therefore advise you to use these models for the tasks they have been fine tuned on. For instance, if you want to use Pix2Struct for UI captioning, you should use the model fine tuned on the UI dataset. If you want to use Pix2Struct for image captioning, you should use the model fine tuned on the natural images captioning dataset and so on.
+
+If you want to use the model to perform conditional text captioning, make sure to use the processor with `add_special_tokens=False`.
+
+This model was contributed by [ybelkada](https://huggingface.co/ybelkada).
+The original code can be found [here](https://github.com/google-research/pix2struct).
+
+## Resources
+
+- [Fine-tuning Notebook](https://github.com/huggingface/notebooks/blob/main/examples/image_captioning_pix2struct.ipynb)
+- [All models](https://huggingface.co/models?search=pix2struct)
+
+## Pix2StructConfig
+
+[[autodoc]] Pix2StructConfig
+ - from_text_vision_configs
+
+## Pix2StructTextConfig
+
+[[autodoc]] Pix2StructTextConfig
+
+## Pix2StructVisionConfig
+
+[[autodoc]] Pix2StructVisionConfig
+
+## Pix2StructProcessor
+
+[[autodoc]] Pix2StructProcessor
+
+## Pix2StructImageProcessor
+
+[[autodoc]] Pix2StructImageProcessor
+ - preprocess
+
+## Pix2StructTextModel
+
+[[autodoc]] Pix2StructTextModel
+ - forward
+
+## Pix2StructVisionModel
+
+[[autodoc]] Pix2StructVisionModel
+ - forward
+
+## Pix2StructForConditionalGeneration
+
+[[autodoc]] Pix2StructForConditionalGeneration
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pixtral.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pixtral.md
new file mode 100644
index 0000000000000000000000000000000000000000..62bdc004c5171853c180002b8b4bb0423f34b4b6
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pixtral.md
@@ -0,0 +1,98 @@
+
+
+# Pixtral
+
+## Overview
+
+The Pixtral model was released by the Mistral AI team in a [blog post](https://mistral.ai/news/pixtral-12b/). Pixtral is a multimodal version of [Mistral](mistral), incorporating a 400 million parameter vision encoder trained from scratch.
+
+The intro from the blog says the following:
+
+*Pixtral is trained to understand both natural images and documents, achieving 52.5% on the MMMU reasoning benchmark, surpassing a number of larger models. The model shows strong abilities in tasks such as chart and figure understanding, document question answering, multimodal reasoning and instruction following. Pixtral is able to ingest images at their natural resolution and aspect ratio, giving the user flexibility on the number of tokens used to process an image. Pixtral is also able to process any number of images in its long context window of 128K tokens. Unlike previous open-source models, Pixtral does not compromise on text benchmark performance to excel in multimodal tasks.*
+
+
+
+ Pixtral architecture. Taken from the blog post.
+
+Tips:
+
+- Pixtral is a multimodal model, taking images and text as input, and producing text as output.
+- This model follows the [Llava](llava) architecture. The model uses [`PixtralVisionModel`] for its vision encoder, and [`MistralForCausalLM`] for its language decoder.
+- The main contribution is the 2d ROPE (rotary position embeddings) on the images, and support for arbitrary image sizes (the images are not padded together nor are they resized).
+- Similar to [Llava](llava), the model internally replaces the `[IMG]` token placeholders by image embeddings from the vision encoder. The format for one or multiple prompts is the following:
+```
+"[INST][IMG]\nWhat are the things I should be cautious about when I visit this place?[/INST]"
+```
+Then, the processor will replace each `[IMG]` token with a number of `[IMG]` tokens that depend on the height and the width of each image. Each *row* of the image is separated by an `[IMG_BREAK]` token, and each image is separated by an `[IMG_END]` token. It's advised to use the `apply_chat_template` method of the processor, which takes care of all of this. See the [usage section](#usage) for more info.
+
+This model was contributed by [amyeroberts](https://huggingface.co/amyeroberts) and [ArthurZ](https://huggingface.co/ArthurZ). The original code can be found [here](https://github.com/vllm-project/vllm/pull/8377).
+
+## Usage
+
+At inference time, it's advised to use the processor's `apply_chat_template` method, which correctly formats the prompt for the model:
+
+```python
+from transformers import AutoProcessor, LlavaForConditionalGeneration
+from PIL import Image
+
+model_id = "mistral-community/pixtral-12b"
+processor = AutoProcessor.from_pretrained(model_id)
+model = LlavaForConditionalGeneration.from_pretrained(model_id).to("cuda")
+
+url_dog = "https://picsum.photos/id/237/200/300"
+url_mountain = "https://picsum.photos/seed/picsum/200/300"
+
+chat = [
+ {
+ "role": "user", "content": [
+ {"type": "text", "content": "Can this animal"},
+ {"type": "image"},
+ {"type": "text", "content": "live here?"},
+ {"type": "image"}
+ ]
+ }
+]
+
+prompt = processor.apply_chat_template(chat)
+inputs = processor(text=prompt, images=[url_dog, url_mountain], return_tensors="pt").to(model.device)
+generate_ids = model.generate(**inputs, max_new_tokens=500)
+output = processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
+```
+
+## PixtralVisionConfig
+
+[[autodoc]] PixtralVisionConfig
+
+## PixtralVisionModel
+
+[[autodoc]] PixtralVisionModel
+ - forward
+
+## PixtralImageProcessor
+
+[[autodoc]] PixtralImageProcessor
+ - preprocess
+
+## PixtralImageProcessorFast
+
+[[autodoc]] PixtralImageProcessorFast
+ - preprocess
+
+## PixtralProcessor
+
+[[autodoc]] PixtralProcessor
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/plbart.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/plbart.md
new file mode 100644
index 0000000000000000000000000000000000000000..61af52e54d0d2166a3b49bb46ebac4ca85d93206
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/plbart.md
@@ -0,0 +1,116 @@
+
+
+# PLBart
+
+## Overview
+
+The PLBART model was proposed in [Unified Pre-training for Program Understanding and Generation](https://arxiv.org/abs/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
+This is a BART-like model which can be used to perform code-summarization, code-generation, and code-translation tasks. The pre-trained model `plbart-base` has been trained using multilingual denoising task
+on Java, Python and English.
+
+According to the abstract
+
+*Code summarization and generation empower conversion between programming language (PL) and natural language (NL),
+while code translation avails the migration of legacy code from one PL to another. This paper introduces PLBART,
+a sequence-to-sequence model capable of performing a broad spectrum of program and language understanding and generation tasks.
+PLBART is pre-trained on an extensive collection of Java and Python functions and associated NL text via denoising autoencoding.
+Experiments on code summarization in the English language, code generation, and code translation in seven programming languages
+show that PLBART outperforms or rivals state-of-the-art models. Moreover, experiments on discriminative tasks, e.g., program
+repair, clone detection, and vulnerable code detection, demonstrate PLBART's effectiveness in program understanding.
+Furthermore, analysis reveals that PLBART learns program syntax, style (e.g., identifier naming convention), logical flow
+(e.g., if block inside an else block is equivalent to else if block) that are crucial to program semantics and thus excels
+even with limited annotations.*
+
+This model was contributed by [gchhablani](https://huggingface.co/gchhablani). The Authors' code can be found [here](https://github.com/wasiahmad/PLBART).
+
+## Usage examples
+
+PLBart is a multilingual encoder-decoder (sequence-to-sequence) model primarily intended for code-to-text, text-to-code, code-to-code tasks. As the
+model is multilingual it expects the sequences in a different format. A special language id token is added in both the
+source and target text. The source text format is `X [eos, src_lang_code]` where `X` is the source text. The
+target text format is `[tgt_lang_code] X [eos]`. `bos` is never used.
+
+However, for fine-tuning, in some cases no language token is provided in cases where a single language is used. Please refer to [the paper](https://arxiv.org/abs/2103.06333) to learn more about this.
+
+In cases where the language code is needed, the regular [`~PLBartTokenizer.__call__`] will encode source text format
+when you pass texts as the first argument or with the keyword argument `text`, and will encode target text format if
+it's passed with the `text_target` keyword argument.
+
+### Supervised training
+
+```python
+>>> from transformers import PLBartForConditionalGeneration, PLBartTokenizer
+
+>>> tokenizer = PLBartTokenizer.from_pretrained("uclanlp/plbart-base", src_lang="en_XX", tgt_lang="python")
+>>> example_python_phrase = "def maximum(a,b,c):NEW_LINE_INDENTreturn max([a,b,c])"
+>>> expected_translation_english = "Returns the maximum value of a b c."
+>>> inputs = tokenizer(example_python_phrase, text_target=expected_translation_english, return_tensors="pt")
+>>> model(**inputs)
+```
+
+### Generation
+
+ While generating the target text set the `decoder_start_token_id` to the target language id. The following
+ example shows how to translate Python to English using the `uclanlp/plbart-python-en_XX` model.
+
+```python
+>>> from transformers import PLBartForConditionalGeneration, PLBartTokenizer
+
+>>> tokenizer = PLBartTokenizer.from_pretrained("uclanlp/plbart-python-en_XX", src_lang="python", tgt_lang="en_XX")
+>>> example_python_phrase = "def maximum(a,b,c):NEW_LINE_INDENTreturn max([a,b,c])"
+>>> inputs = tokenizer(example_python_phrase, return_tensors="pt")
+>>> model = PLBartForConditionalGeneration.from_pretrained("uclanlp/plbart-python-en_XX")
+>>> translated_tokens = model.generate(**inputs, decoder_start_token_id=tokenizer.lang_code_to_id["en_XX"])
+>>> tokenizer.batch_decode(translated_tokens, skip_special_tokens=True)[0]
+"Returns the maximum value of a b c."
+```
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## PLBartConfig
+
+[[autodoc]] PLBartConfig
+
+## PLBartTokenizer
+
+[[autodoc]] PLBartTokenizer
+ - build_inputs_with_special_tokens
+
+## PLBartModel
+
+[[autodoc]] PLBartModel
+ - forward
+
+## PLBartForConditionalGeneration
+
+[[autodoc]] PLBartForConditionalGeneration
+ - forward
+
+## PLBartForSequenceClassification
+
+[[autodoc]] PLBartForSequenceClassification
+ - forward
+
+## PLBartForCausalLM
+
+[[autodoc]] PLBartForCausalLM
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/poolformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/poolformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..823c4412485c4423c80fc1f3f456b54dae2c3523
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/poolformer.md
@@ -0,0 +1,80 @@
+
+
+# PoolFormer
+
+## Overview
+
+The PoolFormer model was proposed in [MetaFormer is Actually What You Need for Vision](https://arxiv.org/abs/2111.11418) by Sea AI Labs. Instead of designing complicated token mixer to achieve SOTA performance, the target of this work is to demonstrate the competence of transformer models largely stem from the general architecture MetaFormer.
+
+The abstract from the paper is the following:
+
+*Transformers have shown great potential in computer vision tasks. A common belief is their attention-based token mixer module contributes most to their competence. However, recent works show the attention-based module in transformers can be replaced by spatial MLPs and the resulted models still perform quite well. Based on this observation, we hypothesize that the general architecture of the transformers, instead of the specific token mixer module, is more essential to the model's performance. To verify this, we deliberately replace the attention module in transformers with an embarrassingly simple spatial pooling operator to conduct only the most basic token mixing. Surprisingly, we observe that the derived model, termed as PoolFormer, achieves competitive performance on multiple computer vision tasks. For example, on ImageNet-1K, PoolFormer achieves 82.1% top-1 accuracy, surpassing well-tuned vision transformer/MLP-like baselines DeiT-B/ResMLP-B24 by 0.3%/1.1% accuracy with 35%/52% fewer parameters and 48%/60% fewer MACs. The effectiveness of PoolFormer verifies our hypothesis and urges us to initiate the concept of "MetaFormer", a general architecture abstracted from transformers without specifying the token mixer. Based on the extensive experiments, we argue that MetaFormer is the key player in achieving superior results for recent transformer and MLP-like models on vision tasks. This work calls for more future research dedicated to improving MetaFormer instead of focusing on the token mixer modules. Additionally, our proposed PoolFormer could serve as a starting baseline for future MetaFormer architecture design.*
+
+The figure below illustrates the architecture of PoolFormer. Taken from the [original paper](https://arxiv.org/abs/2111.11418).
+
+
+
+This model was contributed by [heytanay](https://huggingface.co/heytanay). The original code can be found [here](https://github.com/sail-sg/poolformer).
+
+## Usage tips
+
+- PoolFormer has a hierarchical architecture, where instead of Attention, a simple Average Pooling layer is present. All checkpoints of the model can be found on the [hub](https://huggingface.co/models?other=poolformer).
+- One can use [`PoolFormerImageProcessor`] to prepare images for the model.
+- As most models, PoolFormer comes in different sizes, the details of which can be found in the table below.
+
+| **Model variant** | **Depths** | **Hidden sizes** | **Params (M)** | **ImageNet-1k Top 1** |
+| :---------------: | ------------- | ------------------- | :------------: | :-------------------: |
+| s12 | [2, 2, 6, 2] | [64, 128, 320, 512] | 12 | 77.2 |
+| s24 | [4, 4, 12, 4] | [64, 128, 320, 512] | 21 | 80.3 |
+| s36 | [6, 6, 18, 6] | [64, 128, 320, 512] | 31 | 81.4 |
+| m36 | [6, 6, 18, 6] | [96, 192, 384, 768] | 56 | 82.1 |
+| m48 | [8, 8, 24, 8] | [96, 192, 384, 768] | 73 | 82.5 |
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with PoolFormer.
+
+
+
+- [`PoolFormerForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## PoolFormerConfig
+
+[[autodoc]] PoolFormerConfig
+
+## PoolFormerFeatureExtractor
+
+[[autodoc]] PoolFormerFeatureExtractor
+ - __call__
+
+## PoolFormerImageProcessor
+
+[[autodoc]] PoolFormerImageProcessor
+ - preprocess
+
+## PoolFormerModel
+
+[[autodoc]] PoolFormerModel
+ - forward
+
+## PoolFormerForImageClassification
+
+[[autodoc]] PoolFormerForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pop2piano.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pop2piano.md
new file mode 100644
index 0000000000000000000000000000000000000000..8e7c1fbd34359e84f106a2d2b2f3b18a7e2b5d2a
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pop2piano.md
@@ -0,0 +1,194 @@
+
+
+# Pop2Piano
+
+
+
+## Overview
+
+The Pop2Piano model was proposed in [Pop2Piano : Pop Audio-based Piano Cover Generation](https://arxiv.org/abs/2211.00895) by Jongho Choi and Kyogu Lee.
+
+Piano covers of pop music are widely enjoyed, but generating them from music is not a trivial task. It requires great
+expertise with playing piano as well as knowing different characteristics and melodies of a song. With Pop2Piano you
+can directly generate a cover from a song's audio waveform. It is the first model to directly generate a piano cover
+from pop audio without melody and chord extraction modules.
+
+Pop2Piano is an encoder-decoder Transformer model based on [T5](https://arxiv.org/pdf/1910.10683.pdf). The input audio
+is transformed to its waveform and passed to the encoder, which transforms it to a latent representation. The decoder
+uses these latent representations to generate token ids in an autoregressive way. Each token id corresponds to one of four
+different token types: time, velocity, note and 'special'. The token ids are then decoded to their equivalent MIDI file.
+
+The abstract from the paper is the following:
+
+*Piano covers of pop music are enjoyed by many people. However, the
+task of automatically generating piano covers of pop music is still
+understudied. This is partly due to the lack of synchronized
+{Pop, Piano Cover} data pairs, which made it challenging to apply
+the latest data-intensive deep learning-based methods. To leverage
+the power of the data-driven approach, we make a large amount of
+paired and synchronized {Pop, Piano Cover} data using an automated
+pipeline. In this paper, we present Pop2Piano, a Transformer network
+that generates piano covers given waveforms of pop music. To the best
+of our knowledge, this is the first model to generate a piano cover
+directly from pop audio without using melody and chord extraction
+modules. We show that Pop2Piano, trained with our dataset, is capable
+of producing plausible piano covers.*
+
+This model was contributed by [Susnato Dhar](https://huggingface.co/susnato).
+The original code can be found [here](https://github.com/sweetcocoa/pop2piano).
+
+## Usage tips
+
+* To use Pop2Piano, you will need to install the 🤗 Transformers library, as well as the following third party modules:
+```bash
+pip install pretty-midi==0.2.9 essentia==2.1b6.dev1034 librosa scipy
+```
+Please note that you may need to restart your runtime after installation.
+* Pop2Piano is an Encoder-Decoder based model like T5.
+* Pop2Piano can be used to generate midi-audio files for a given audio sequence.
+* Choosing different composers in `Pop2PianoForConditionalGeneration.generate()` can lead to variety of different results.
+* Setting the sampling rate to 44.1 kHz when loading the audio file can give good performance.
+* Though Pop2Piano was mainly trained on Korean Pop music, it also does pretty well on other Western Pop or Hip Hop songs.
+
+## Examples
+
+- Example using HuggingFace Dataset:
+
+```python
+>>> from datasets import load_dataset
+>>> from transformers import Pop2PianoForConditionalGeneration, Pop2PianoProcessor
+
+>>> model = Pop2PianoForConditionalGeneration.from_pretrained("sweetcocoa/pop2piano")
+>>> processor = Pop2PianoProcessor.from_pretrained("sweetcocoa/pop2piano")
+>>> ds = load_dataset("sweetcocoa/pop2piano_ci", split="test")
+
+>>> inputs = processor(
+... audio=ds["audio"][0]["array"], sampling_rate=ds["audio"][0]["sampling_rate"], return_tensors="pt"
+... )
+>>> model_output = model.generate(input_features=inputs["input_features"], composer="composer1")
+>>> tokenizer_output = processor.batch_decode(
+... token_ids=model_output, feature_extractor_output=inputs
+... )["pretty_midi_objects"][0]
+>>> tokenizer_output.write("./Outputs/midi_output.mid")
+```
+
+- Example using your own audio file:
+
+```python
+>>> import librosa
+>>> from transformers import Pop2PianoForConditionalGeneration, Pop2PianoProcessor
+
+>>> audio, sr = librosa.load("", sr=44100) # feel free to change the sr to a suitable value.
+>>> model = Pop2PianoForConditionalGeneration.from_pretrained("sweetcocoa/pop2piano")
+>>> processor = Pop2PianoProcessor.from_pretrained("sweetcocoa/pop2piano")
+
+>>> inputs = processor(audio=audio, sampling_rate=sr, return_tensors="pt")
+>>> model_output = model.generate(input_features=inputs["input_features"], composer="composer1")
+>>> tokenizer_output = processor.batch_decode(
+... token_ids=model_output, feature_extractor_output=inputs
+... )["pretty_midi_objects"][0]
+>>> tokenizer_output.write("./Outputs/midi_output.mid")
+```
+
+- Example of processing multiple audio files in batch:
+
+```python
+>>> import librosa
+>>> from transformers import Pop2PianoForConditionalGeneration, Pop2PianoProcessor
+
+>>> # feel free to change the sr to a suitable value.
+>>> audio1, sr1 = librosa.load("", sr=44100)
+>>> audio2, sr2 = librosa.load("", sr=44100)
+>>> model = Pop2PianoForConditionalGeneration.from_pretrained("sweetcocoa/pop2piano")
+>>> processor = Pop2PianoProcessor.from_pretrained("sweetcocoa/pop2piano")
+
+>>> inputs = processor(audio=[audio1, audio2], sampling_rate=[sr1, sr2], return_attention_mask=True, return_tensors="pt")
+>>> # Since we now generating in batch(2 audios) we must pass the attention_mask
+>>> model_output = model.generate(
+... input_features=inputs["input_features"],
+... attention_mask=inputs["attention_mask"],
+... composer="composer1",
+... )
+>>> tokenizer_output = processor.batch_decode(
+... token_ids=model_output, feature_extractor_output=inputs
+... )["pretty_midi_objects"]
+
+>>> # Since we now have 2 generated MIDI files
+>>> tokenizer_output[0].write("./Outputs/midi_output1.mid")
+>>> tokenizer_output[1].write("./Outputs/midi_output2.mid")
+```
+
+
+- Example of processing multiple audio files in batch (Using `Pop2PianoFeatureExtractor` and `Pop2PianoTokenizer`):
+
+```python
+>>> import librosa
+>>> from transformers import Pop2PianoForConditionalGeneration, Pop2PianoFeatureExtractor, Pop2PianoTokenizer
+
+>>> # feel free to change the sr to a suitable value.
+>>> audio1, sr1 = librosa.load("", sr=44100)
+>>> audio2, sr2 = librosa.load("", sr=44100)
+>>> model = Pop2PianoForConditionalGeneration.from_pretrained("sweetcocoa/pop2piano")
+>>> feature_extractor = Pop2PianoFeatureExtractor.from_pretrained("sweetcocoa/pop2piano")
+>>> tokenizer = Pop2PianoTokenizer.from_pretrained("sweetcocoa/pop2piano")
+
+>>> inputs = feature_extractor(
+... audio=[audio1, audio2],
+... sampling_rate=[sr1, sr2],
+... return_attention_mask=True,
+... return_tensors="pt",
+... )
+>>> # Since we now generating in batch(2 audios) we must pass the attention_mask
+>>> model_output = model.generate(
+... input_features=inputs["input_features"],
+... attention_mask=inputs["attention_mask"],
+... composer="composer1",
+... )
+>>> tokenizer_output = tokenizer.batch_decode(
+... token_ids=model_output, feature_extractor_output=inputs
+... )["pretty_midi_objects"]
+
+>>> # Since we now have 2 generated MIDI files
+>>> tokenizer_output[0].write("./Outputs/midi_output1.mid")
+>>> tokenizer_output[1].write("./Outputs/midi_output2.mid")
+```
+
+
+## Pop2PianoConfig
+
+[[autodoc]] Pop2PianoConfig
+
+## Pop2PianoFeatureExtractor
+
+[[autodoc]] Pop2PianoFeatureExtractor
+ - __call__
+
+## Pop2PianoForConditionalGeneration
+
+[[autodoc]] Pop2PianoForConditionalGeneration
+ - forward
+ - generate
+
+## Pop2PianoTokenizer
+
+[[autodoc]] Pop2PianoTokenizer
+ - __call__
+
+## Pop2PianoProcessor
+
+[[autodoc]] Pop2PianoProcessor
+ - __call__
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/prophetnet.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/prophetnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..764c3acb0674dbc083c312bb38c213419d26b037
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/prophetnet.md
@@ -0,0 +1,103 @@
+
+
+# ProphetNet
+
+
+
+## Overview
+
+The ProphetNet model was proposed in [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training,](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei
+Zhang, Ming Zhou on 13 Jan, 2020.
+
+ProphetNet is an encoder-decoder model and can predict n-future tokens for "ngram" language modeling instead of just
+the next token.
+
+The abstract from the paper is the following:
+
+*In this paper, we present a new sequence-to-sequence pretraining model called ProphetNet, which introduces a novel
+self-supervised objective named future n-gram prediction and the proposed n-stream self-attention mechanism. Instead of
+the optimization of one-step ahead prediction in traditional sequence-to-sequence model, the ProphetNet is optimized by
+n-step ahead prediction which predicts the next n tokens simultaneously based on previous context tokens at each time
+step. The future n-gram prediction explicitly encourages the model to plan for the future tokens and prevent
+overfitting on strong local correlations. We pre-train ProphetNet using a base scale dataset (16GB) and a large scale
+dataset (160GB) respectively. Then we conduct experiments on CNN/DailyMail, Gigaword, and SQuAD 1.1 benchmarks for
+abstractive summarization and question generation tasks. Experimental results show that ProphetNet achieves new
+state-of-the-art results on all these datasets compared to the models using the same scale pretraining corpus.*
+
+The Authors' code can be found [here](https://github.com/microsoft/ProphetNet).
+
+## Usage tips
+
+- ProphetNet is a model with absolute position embeddings so it's usually advised to pad the inputs on the right rather than
+ the left.
+- The model architecture is based on the original Transformer, but replaces the “standard” self-attention mechanism in the decoder by a main self-attention mechanism and a self and n-stream (predict) self-attention mechanism.
+
+## Resources
+
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## ProphetNetConfig
+
+[[autodoc]] ProphetNetConfig
+
+## ProphetNetTokenizer
+
+[[autodoc]] ProphetNetTokenizer
+
+## ProphetNet specific outputs
+
+[[autodoc]] models.prophetnet.modeling_prophetnet.ProphetNetSeq2SeqLMOutput
+
+[[autodoc]] models.prophetnet.modeling_prophetnet.ProphetNetSeq2SeqModelOutput
+
+[[autodoc]] models.prophetnet.modeling_prophetnet.ProphetNetDecoderModelOutput
+
+[[autodoc]] models.prophetnet.modeling_prophetnet.ProphetNetDecoderLMOutput
+
+## ProphetNetModel
+
+[[autodoc]] ProphetNetModel
+ - forward
+
+## ProphetNetEncoder
+
+[[autodoc]] ProphetNetEncoder
+ - forward
+
+## ProphetNetDecoder
+
+[[autodoc]] ProphetNetDecoder
+ - forward
+
+## ProphetNetForConditionalGeneration
+
+[[autodoc]] ProphetNetForConditionalGeneration
+ - forward
+
+## ProphetNetForCausalLM
+
+[[autodoc]] ProphetNetForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pvt.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pvt.md
new file mode 100644
index 0000000000000000000000000000000000000000..3e88a24999f7597ae9b149ffc3f8136005d129e0
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pvt.md
@@ -0,0 +1,71 @@
+
+
+# Pyramid Vision Transformer (PVT)
+
+## Overview
+
+The PVT model was proposed in
+[Pyramid Vision Transformer: A Versatile Backbone for Dense Prediction without Convolutions](https://arxiv.org/abs/2102.12122)
+by Wenhai Wang, Enze Xie, Xiang Li, Deng-Ping Fan, Kaitao Song, Ding Liang, Tong Lu, Ping Luo, Ling Shao. The PVT is a type of
+vision transformer that utilizes a pyramid structure to make it an effective backbone for dense prediction tasks. Specifically
+it allows for more fine-grained inputs (4 x 4 pixels per patch) to be used, while simultaneously shrinking the sequence length
+of the Transformer as it deepens - reducing the computational cost. Additionally, a spatial-reduction attention (SRA) layer
+is used to further reduce the resource consumption when learning high-resolution features.
+
+The abstract from the paper is the following:
+
+*Although convolutional neural networks (CNNs) have achieved great success in computer vision, this work investigates a
+simpler, convolution-free backbone network useful for many dense prediction tasks. Unlike the recently proposed Vision
+Transformer (ViT) that was designed for image classification specifically, we introduce the Pyramid Vision Transformer
+(PVT), which overcomes the difficulties of porting Transformer to various dense prediction tasks. PVT has several
+merits compared to current state of the arts. Different from ViT that typically yields low resolution outputs and
+incurs high computational and memory costs, PVT not only can be trained on dense partitions of an image to achieve high
+output resolution, which is important for dense prediction, but also uses a progressive shrinking pyramid to reduce the
+computations of large feature maps. PVT inherits the advantages of both CNN and Transformer, making it a unified
+backbone for various vision tasks without convolutions, where it can be used as a direct replacement for CNN backbones.
+We validate PVT through extensive experiments, showing that it boosts the performance of many downstream tasks, including
+object detection, instance and semantic segmentation. For example, with a comparable number of parameters, PVT+RetinaNet
+achieves 40.4 AP on the COCO dataset, surpassing ResNet50+RetinNet (36.3 AP) by 4.1 absolute AP (see Figure 2). We hope
+that PVT could serve as an alternative and useful backbone for pixel-level predictions and facilitate future research.*
+
+This model was contributed by [Xrenya](https://huggingface.co/Xrenya). The original code can be found [here](https://github.com/whai362/PVT).
+
+
+- PVTv1 on ImageNet-1K
+
+| **Model variant** |**Size** |**Acc@1**|**Params (M)**|
+|--------------------|:-------:|:-------:|:------------:|
+| PVT-Tiny | 224 | 75.1 | 13.2 |
+| PVT-Small | 224 | 79.8 | 24.5 |
+| PVT-Medium | 224 | 81.2 | 44.2 |
+| PVT-Large | 224 | 81.7 | 61.4 |
+
+
+## PvtConfig
+
+[[autodoc]] PvtConfig
+
+## PvtImageProcessor
+
+[[autodoc]] PvtImageProcessor
+ - preprocess
+
+## PvtForImageClassification
+
+[[autodoc]] PvtForImageClassification
+ - forward
+
+## PvtModel
+
+[[autodoc]] PvtModel
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pvt_v2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pvt_v2.md
new file mode 100644
index 0000000000000000000000000000000000000000..4b580491ea1e7e740d59d5fd838767b595e23f04
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pvt_v2.md
@@ -0,0 +1,110 @@
+
+
+# Pyramid Vision Transformer V2 (PVTv2)
+
+## Overview
+
+The PVTv2 model was proposed in
+[PVT v2: Improved Baselines with Pyramid Vision Transformer](https://arxiv.org/abs/2106.13797) by Wenhai Wang, Enze Xie, Xiang Li, Deng-Ping Fan, Kaitao Song, Ding Liang, Tong Lu, Ping Luo, and Ling Shao. As an improved variant of PVT, it eschews position embeddings, relying instead on positional information encoded through zero-padding and overlapping patch embeddings. This lack of reliance on position embeddings simplifies the architecture, and enables running inference at any resolution without needing to interpolate them.
+
+The PVTv2 encoder structure has been successfully deployed to achieve state-of-the-art scores in [Segformer](https://arxiv.org/abs/2105.15203) for semantic segmentation, [GLPN](https://arxiv.org/abs/2201.07436) for monocular depth, and [Panoptic Segformer](https://arxiv.org/abs/2109.03814) for panoptic segmentation.
+
+PVTv2 belongs to a family of models called [hierarchical transformers](https://natecibik.medium.com/the-rise-of-vision-transformers-f623c980419f) , which make adaptations to transformer layers in order to generate multi-scale feature maps. Unlike the columnal structure of Vision Transformer ([ViT](https://arxiv.org/abs/2010.11929)) which loses fine-grained detail, multi-scale feature maps are known preserve this detail and aid performance in dense prediction tasks. In the case of PVTv2, this is achieved by generating image patch tokens using 2D convolution with overlapping kernels in each encoder layer.
+
+The multi-scale features of hierarchical transformers allow them to be easily swapped in for traditional workhorse computer vision backbone models like ResNet in larger architectures. Both Segformer and Panoptic Segformer demonstrated that configurations using PVTv2 for a backbone consistently outperformed those with similarly sized ResNet backbones.
+
+Another powerful feature of the PVTv2 is the complexity reduction in the self-attention layers called Spatial Reduction Attention (SRA), which uses 2D convolution layers to project hidden states to a smaller resolution before attending to them with the queries, improving the $O(n^2)$ complexity of self-attention to $O(n^2/R)$, with $R$ being the spatial reduction ratio (`sr_ratio`, aka kernel size and stride in the 2D convolution).
+
+SRA was introduced in PVT, and is the default attention complexity reduction method used in PVTv2. However, PVTv2 also introduced the option of using a self-attention mechanism with linear complexity related to image size, which they called "Linear SRA". This method uses average pooling to reduce the hidden states to a fixed size that is invariant to their original resolution (although this is inherently more lossy than regular SRA). This option can be enabled by setting `linear_attention` to `True` in the PVTv2Config.
+
+### Abstract from the paper:
+
+*Transformer recently has presented encouraging progress in computer vision. In this work, we present new baselines by improving the original Pyramid Vision Transformer (PVT v1) by adding three designs, including (1) linear complexity attention layer, (2) overlapping patch embedding, and (3) convolutional feed-forward network. With these modifications, PVT v2 reduces the computational complexity of PVT v1 to linear and achieves significant improvements on fundamental vision tasks such as classification, detection, and segmentation. Notably, the proposed PVT v2 achieves comparable or better performances than recent works such as Swin Transformer. We hope this work will facilitate state-of-the-art Transformer researches in computer vision. Code is available at https://github.com/whai362/PVT.*
+
+This model was contributed by [FoamoftheSea](https://huggingface.co/FoamoftheSea). The original code can be found [here](https://github.com/whai362/PVT).
+
+## Usage tips
+
+- [PVTv2](https://arxiv.org/abs/2106.13797) is a hierarchical transformer model which has demonstrated powerful performance in image classification and multiple other tasks, used as a backbone for semantic segmentation in [Segformer](https://arxiv.org/abs/2105.15203), monocular depth estimation in [GLPN](https://arxiv.org/abs/2201.07436), and panoptic segmentation in [Panoptic Segformer](https://arxiv.org/abs/2109.03814), consistently showing higher performance than similar ResNet configurations.
+- Hierarchical transformers like PVTv2 achieve superior data and parameter efficiency on image data compared with pure transformer architectures by incorporating design elements of convolutional neural networks (CNNs) into their encoders. This creates a best-of-both-worlds architecture that infuses the useful inductive biases of CNNs like translation equivariance and locality into the network while still enjoying the benefits of dynamic data response and global relationship modeling provided by the self-attention mechanism of [transformers](https://arxiv.org/abs/1706.03762).
+- PVTv2 uses overlapping patch embeddings to create multi-scale feature maps, which are infused with location information using zero-padding and depth-wise convolutions.
+- To reduce the complexity in the attention layers, PVTv2 performs a spatial reduction on the hidden states using either strided 2D convolution (SRA) or fixed-size average pooling (Linear SRA). Although inherently more lossy, Linear SRA provides impressive performance with a linear complexity with respect to image size. To use Linear SRA in the self-attention layers, set `linear_attention=True` in the `PvtV2Config`.
+- [`PvtV2Model`] is the hierarchical transformer encoder (which is also often referred to as Mix Transformer or MiT in the literature). [`PvtV2ForImageClassification`] adds a simple classifier head on top to perform Image Classification. [`PvtV2Backbone`] can be used with the [`AutoBackbone`] system in larger architectures like Deformable DETR.
+- ImageNet pretrained weights for all model sizes can be found on the [hub](https://huggingface.co/models?other=pvt_v2).
+
+ The best way to get started with the PVTv2 is to load the pretrained checkpoint with the size of your choosing using `AutoModelForImageClassification`:
+```python
+import requests
+import torch
+
+from transformers import AutoModelForImageClassification, AutoImageProcessor
+from PIL import Image
+
+model = AutoModelForImageClassification.from_pretrained("OpenGVLab/pvt_v2_b0")
+image_processor = AutoImageProcessor.from_pretrained("OpenGVLab/pvt_v2_b0")
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+processed = image_processor(image)
+outputs = model(torch.tensor(processed["pixel_values"]))
+```
+
+To use the PVTv2 as a backbone for more complex architectures like DeformableDETR, you can use AutoBackbone (this model would need fine-tuning as you're replacing the backbone in the pretrained model):
+
+```python
+import requests
+import torch
+
+from transformers import AutoConfig, AutoModelForObjectDetection, AutoImageProcessor
+from PIL import Image
+
+model = AutoModelForObjectDetection.from_config(
+ config=AutoConfig.from_pretrained(
+ "SenseTime/deformable-detr",
+ backbone_config=AutoConfig.from_pretrained("OpenGVLab/pvt_v2_b5"),
+ use_timm_backbone=False
+ ),
+)
+
+image_processor = AutoImageProcessor.from_pretrained("SenseTime/deformable-detr")
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+processed = image_processor(image)
+outputs = model(torch.tensor(processed["pixel_values"]))
+```
+
+[PVTv2](https://github.com/whai362/PVT/tree/v2) performance on ImageNet-1K by model size (B0-B5):
+
+| Method | Size | Acc@1 | #Params (M) |
+|------------------|:----:|:-----:|:-----------:|
+| PVT-V2-B0 | 224 | 70.5 | 3.7 |
+| PVT-V2-B1 | 224 | 78.7 | 14.0 |
+| PVT-V2-B2-Linear | 224 | 82.1 | 22.6 |
+| PVT-V2-B2 | 224 | 82.0 | 25.4 |
+| PVT-V2-B3 | 224 | 83.1 | 45.2 |
+| PVT-V2-B4 | 224 | 83.6 | 62.6 |
+| PVT-V2-B5 | 224 | 83.8 | 82.0 |
+
+
+## PvtV2Config
+
+[[autodoc]] PvtV2Config
+
+## PvtForImageClassification
+
+[[autodoc]] PvtV2ForImageClassification
+ - forward
+
+## PvtModel
+
+[[autodoc]] PvtV2Model
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/qdqbert.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/qdqbert.md
new file mode 100644
index 0000000000000000000000000000000000000000..ca718f34af4a32a92988dea4c23aad4a1dd09ba4
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/qdqbert.md
@@ -0,0 +1,176 @@
+
+
+# QDQBERT
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The QDQBERT model can be referenced in [Integer Quantization for Deep Learning Inference: Principles and Empirical
+Evaluation](https://arxiv.org/abs/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius
+Micikevicius.
+
+The abstract from the paper is the following:
+
+*Quantization techniques can reduce the size of Deep Neural Networks and improve inference latency and throughput by
+taking advantage of high throughput integer instructions. In this paper we review the mathematical aspects of
+quantization parameters and evaluate their choices on a wide range of neural network models for different application
+domains, including vision, speech, and language. We focus on quantization techniques that are amenable to acceleration
+by processors with high-throughput integer math pipelines. We also present a workflow for 8-bit quantization that is
+able to maintain accuracy within 1% of the floating-point baseline on all networks studied, including models that are
+more difficult to quantize, such as MobileNets and BERT-large.*
+
+This model was contributed by [shangz](https://huggingface.co/shangz).
+
+## Usage tips
+
+- QDQBERT model adds fake quantization operations (pair of QuantizeLinear/DequantizeLinear ops) to (i) linear layer
+ inputs and weights, (ii) matmul inputs, (iii) residual add inputs, in BERT model.
+- QDQBERT requires the dependency of [Pytorch Quantization Toolkit](https://github.com/NVIDIA/TensorRT/tree/master/tools/pytorch-quantization). To install `pip install pytorch-quantization --extra-index-url https://pypi.ngc.nvidia.com`
+- QDQBERT model can be loaded from any checkpoint of HuggingFace BERT model (for example *google-bert/bert-base-uncased*), and
+ perform Quantization Aware Training/Post Training Quantization.
+- A complete example of using QDQBERT model to perform Quatization Aware Training and Post Training Quantization for
+ SQUAD task can be found at [transformers/examples/research_projects/quantization-qdqbert/](examples/research_projects/quantization-qdqbert/).
+
+### Set default quantizers
+
+QDQBERT model adds fake quantization operations (pair of QuantizeLinear/DequantizeLinear ops) to BERT by
+`TensorQuantizer` in [Pytorch Quantization Toolkit](https://github.com/NVIDIA/TensorRT/tree/master/tools/pytorch-quantization). `TensorQuantizer` is the module
+for quantizing tensors, with `QuantDescriptor` defining how the tensor should be quantized. Refer to [Pytorch
+Quantization Toolkit userguide](https://docs.nvidia.com/deeplearning/tensorrt/pytorch-quantization-toolkit/docs/userguide.html) for more details.
+
+Before creating QDQBERT model, one has to set the default `QuantDescriptor` defining default tensor quantizers.
+
+Example:
+
+```python
+>>> import pytorch_quantization.nn as quant_nn
+>>> from pytorch_quantization.tensor_quant import QuantDescriptor
+
+>>> # The default tensor quantizer is set to use Max calibration method
+>>> input_desc = QuantDescriptor(num_bits=8, calib_method="max")
+>>> # The default tensor quantizer is set to be per-channel quantization for weights
+>>> weight_desc = QuantDescriptor(num_bits=8, axis=((0,)))
+>>> quant_nn.QuantLinear.set_default_quant_desc_input(input_desc)
+>>> quant_nn.QuantLinear.set_default_quant_desc_weight(weight_desc)
+```
+
+### Calibration
+
+Calibration is the terminology of passing data samples to the quantizer and deciding the best scaling factors for
+tensors. After setting up the tensor quantizers, one can use the following example to calibrate the model:
+
+```python
+>>> # Find the TensorQuantizer and enable calibration
+>>> for name, module in model.named_modules():
+... if name.endswith("_input_quantizer"):
+... module.enable_calib()
+... module.disable_quant() # Use full precision data to calibrate
+
+>>> # Feeding data samples
+>>> model(x)
+>>> # ...
+
+>>> # Finalize calibration
+>>> for name, module in model.named_modules():
+... if name.endswith("_input_quantizer"):
+... module.load_calib_amax()
+... module.enable_quant()
+
+>>> # If running on GPU, it needs to call .cuda() again because new tensors will be created by calibration process
+>>> model.cuda()
+
+>>> # Keep running the quantized model
+>>> # ...
+```
+
+### Export to ONNX
+
+The goal of exporting to ONNX is to deploy inference by [TensorRT](https://developer.nvidia.com/tensorrt). Fake
+quantization will be broken into a pair of QuantizeLinear/DequantizeLinear ONNX ops. After setting static member of
+TensorQuantizer to use Pytorch’s own fake quantization functions, fake quantized model can be exported to ONNX, follow
+the instructions in [torch.onnx](https://pytorch.org/docs/stable/onnx.html). Example:
+
+```python
+>>> from pytorch_quantization.nn import TensorQuantizer
+
+>>> TensorQuantizer.use_fb_fake_quant = True
+
+>>> # Load the calibrated model
+>>> ...
+>>> # ONNX export
+>>> torch.onnx.export(...)
+```
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## QDQBertConfig
+
+[[autodoc]] QDQBertConfig
+
+## QDQBertModel
+
+[[autodoc]] QDQBertModel
+ - forward
+
+## QDQBertLMHeadModel
+
+[[autodoc]] QDQBertLMHeadModel
+ - forward
+
+## QDQBertForMaskedLM
+
+[[autodoc]] QDQBertForMaskedLM
+ - forward
+
+## QDQBertForSequenceClassification
+
+[[autodoc]] QDQBertForSequenceClassification
+ - forward
+
+## QDQBertForNextSentencePrediction
+
+[[autodoc]] QDQBertForNextSentencePrediction
+ - forward
+
+## QDQBertForMultipleChoice
+
+[[autodoc]] QDQBertForMultipleChoice
+ - forward
+
+## QDQBertForTokenClassification
+
+[[autodoc]] QDQBertForTokenClassification
+ - forward
+
+## QDQBertForQuestionAnswering
+
+[[autodoc]] QDQBertForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/qwen2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/qwen2.md
new file mode 100644
index 0000000000000000000000000000000000000000..78138413c7fb3a012bfc46487a4ed1d517e60a78
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/qwen2.md
@@ -0,0 +1,92 @@
+
+
+# Qwen2
+
+## Overview
+
+Qwen2 is the new model series of large language models from the Qwen team. Previously, we released the Qwen series, including Qwen2-0.5B, Qwen2-1.5B, Qwen2-7B, Qwen2-57B-A14B, Qwen2-72B, Qwen2-Audio, etc.
+
+### Model Details
+
+Qwen2 is a language model series including decoder language models of different model sizes. For each size, we release the base language model and the aligned chat model. It is based on the Transformer architecture with SwiGLU activation, attention QKV bias, group query attention, mixture of sliding window attention and full attention, etc. Additionally, we have an improved tokenizer adaptive to multiple natural languages and codes.
+
+
+## Usage tips
+
+`Qwen2-7B` and `Qwen2-7B-Instruct` can be found on the [Huggingface Hub](https://huggingface.co/Qwen)
+
+In the following, we demonstrate how to use `Qwen2-7B-Instruct` for the inference. Note that we have used the ChatML format for dialog, in this demo we show how to leverage `apply_chat_template` for this purpose.
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+>>> device = "cuda" # the device to load the model onto
+
+>>> model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen2-7B-Instruct", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen2-7B-Instruct")
+
+>>> prompt = "Give me a short introduction to large language model."
+
+>>> messages = [{"role": "user", "content": prompt}]
+
+>>> text = tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
+
+>>> model_inputs = tokenizer([text], return_tensors="pt").to(device)
+
+>>> generated_ids = model.generate(model_inputs.input_ids, max_new_tokens=512, do_sample=True)
+
+>>> generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(model_inputs.input_ids, generated_ids)]
+
+>>> response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+```
+
+## Qwen2Config
+
+[[autodoc]] Qwen2Config
+
+## Qwen2Tokenizer
+
+[[autodoc]] Qwen2Tokenizer
+ - save_vocabulary
+
+## Qwen2TokenizerFast
+
+[[autodoc]] Qwen2TokenizerFast
+
+## Qwen2Model
+
+[[autodoc]] Qwen2Model
+ - forward
+
+## Qwen2ForCausalLM
+
+[[autodoc]] Qwen2ForCausalLM
+ - forward
+
+## Qwen2ForSequenceClassification
+
+[[autodoc]] Qwen2ForSequenceClassification
+ - forward
+
+## Qwen2ForTokenClassification
+
+[[autodoc]] Qwen2ForTokenClassification
+ - forward
+
+## Qwen2ForQuestionAnswering
+
+[[autodoc]] Qwen2ForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/qwen2_audio.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/qwen2_audio.md
new file mode 100644
index 0000000000000000000000000000000000000000..f399a7e7320c17228768ce46e61e9e4ae2e623ad
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/qwen2_audio.md
@@ -0,0 +1,198 @@
+
+
+# Qwen2Audio
+
+## Overview
+
+The Qwen2-Audio is the new model series of large audio-language models from the Qwen team. Qwen2-Audio is capable of accepting various audio signal inputs and performing audio analysis or direct textual responses with regard to speech instructions. We introduce two distinct audio interaction modes:
+
+* voice chat: users can freely engage in voice interactions with Qwen2-Audio without text input
+* audio analysis: users could provide audio and text instructions for analysis during the interaction
+
+It was proposed in [Qwen2-Audio Technical Report](https://arxiv.org/abs/2407.10759) by Yunfei Chu, Jin Xu, Qian Yang, Haojie Wei, Xipin Wei, Zhifang Guo, Yichong Leng, Yuanjun Lv, Jinzheng He, Junyang Lin, Chang Zhou, Jingren Zhou.
+
+The abstract from the paper is the following:
+
+*We introduce the latest progress of Qwen-Audio, a large-scale audio-language model called Qwen2-Audio, which is capable of accepting various audio signal inputs and performing audio analysis or direct textual responses with regard to speech instructions. In contrast to complex hierarchical tags, we have simplified the pre-training process by utilizing natural language prompts for different data and tasks, and have further expanded the data volume. We have boosted the instruction-following capability of Qwen2-Audio and implemented two distinct audio interaction modes for voice chat and audio analysis. In the voice chat mode, users can freely engage in voice interactions with Qwen2-Audio without text input. In the audio analysis mode, users could provide audio and text instructions for analysis during the interaction. Note that we do not use any system prompts to switch between voice chat and audio analysis modes. Qwen2-Audio is capable of intelligently comprehending the content within audio and following voice commands to respond appropriately. For instance, in an audio segment that simultaneously contains sounds, multi-speaker conversations, and a voice command, Qwen2-Audio can directly understand the command and provide an interpretation and response to the audio. Additionally, DPO has optimized the model's performance in terms of factuality and adherence to desired behavior. According to the evaluation results from AIR-Bench, Qwen2-Audio outperformed previous SOTAs, such as Gemini-1.5-pro, in tests focused on audio-centric instruction-following capabilities. Qwen2-Audio is open-sourced with the aim of fostering the advancement of the multi-modal language community. *
+
+
+## Usage tips
+
+`Qwen2-Audio-7B` and `Qwen2-Audio-7B-Instruct` can be found on the [Huggingface Hub](https://huggingface.co/Qwen)
+
+In the following, we demonstrate how to use `Qwen2-Audio-7B-Instruct` for the inference, supporting both voice chat and audio analysis modes. Note that we have used the ChatML format for dialog, in this demo we show how to leverage `apply_chat_template` for this purpose.
+
+### Voice Chat Inference
+In the voice chat mode, users can freely engage in voice interactions with Qwen2-Audio without text input:
+```python
+from io import BytesIO
+from urllib.request import urlopen
+import librosa
+from transformers import Qwen2AudioForConditionalGeneration, AutoProcessor
+
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-Audio-7B-Instruct")
+model = Qwen2AudioForConditionalGeneration.from_pretrained("Qwen/Qwen2-Audio-7B-Instruct", device_map="auto")
+
+conversation = [
+ {"role": "user", "content": [
+ {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/guess_age_gender.wav"},
+ ]},
+ {"role": "assistant", "content": "Yes, the speaker is female and in her twenties."},
+ {"role": "user", "content": [
+ {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/translate_to_chinese.wav"},
+ ]},
+]
+text = processor.apply_chat_template(conversation, add_generation_prompt=True, tokenize=False)
+audios = []
+for message in conversation:
+ if isinstance(message["content"], list):
+ for ele in message["content"]:
+ if ele["type"] == "audio":
+ audios.append(librosa.load(
+ BytesIO(urlopen(ele['audio_url']).read()),
+ sr=processor.feature_extractor.sampling_rate)[0]
+ )
+
+inputs = processor(text=text, audios=audios, return_tensors="pt", padding=True)
+inputs.input_ids = inputs.input_ids.to("cuda")
+
+generate_ids = model.generate(**inputs, max_length=256)
+generate_ids = generate_ids[:, inputs.input_ids.size(1):]
+
+response = processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
+```
+
+### Audio Analysis Inference
+In the audio analysis, users could provide both audio and text instructions for analysis:
+```python
+from io import BytesIO
+from urllib.request import urlopen
+import librosa
+from transformers import Qwen2AudioForConditionalGeneration, AutoProcessor
+
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-Audio-7B-Instruct")
+model = Qwen2AudioForConditionalGeneration.from_pretrained("Qwen/Qwen2-Audio-7B-Instruct", device_map="auto")
+
+conversation = [
+ {'role': 'system', 'content': 'You are a helpful assistant.'},
+ {"role": "user", "content": [
+ {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/glass-breaking-151256.mp3"},
+ {"type": "text", "text": "What's that sound?"},
+ ]},
+ {"role": "assistant", "content": "It is the sound of glass shattering."},
+ {"role": "user", "content": [
+ {"type": "text", "text": "What can you do when you hear that?"},
+ ]},
+ {"role": "assistant", "content": "Stay alert and cautious, and check if anyone is hurt or if there is any damage to property."},
+ {"role": "user", "content": [
+ {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/1272-128104-0000.flac"},
+ {"type": "text", "text": "What does the person say?"},
+ ]},
+]
+text = processor.apply_chat_template(conversation, add_generation_prompt=True, tokenize=False)
+audios = []
+for message in conversation:
+ if isinstance(message["content"], list):
+ for ele in message["content"]:
+ if ele["type"] == "audio":
+ audios.append(
+ librosa.load(
+ BytesIO(urlopen(ele['audio_url']).read()),
+ sr=processor.feature_extractor.sampling_rate)[0]
+ )
+
+inputs = processor(text=text, audios=audios, return_tensors="pt", padding=True)
+inputs.input_ids = inputs.input_ids.to("cuda")
+
+generate_ids = model.generate(**inputs, max_length=256)
+generate_ids = generate_ids[:, inputs.input_ids.size(1):]
+
+response = processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
+```
+
+### Batch Inference
+We also support batch inference:
+```python
+from io import BytesIO
+from urllib.request import urlopen
+import librosa
+from transformers import Qwen2AudioForConditionalGeneration, AutoProcessor
+
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-Audio-7B-Instruct")
+model = Qwen2AudioForConditionalGeneration.from_pretrained("Qwen/Qwen2-Audio-7B-Instruct", device_map="auto")
+
+conversation1 = [
+ {"role": "user", "content": [
+ {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/glass-breaking-151256.mp3"},
+ {"type": "text", "text": "What's that sound?"},
+ ]},
+ {"role": "assistant", "content": "It is the sound of glass shattering."},
+ {"role": "user", "content": [
+ {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/f2641_0_throatclearing.wav"},
+ {"type": "text", "text": "What can you hear?"},
+ ]}
+]
+
+conversation2 = [
+ {"role": "user", "content": [
+ {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/1272-128104-0000.flac"},
+ {"type": "text", "text": "What does the person say?"},
+ ]},
+]
+
+conversations = [conversation1, conversation2]
+
+text = [processor.apply_chat_template(conversation, add_generation_prompt=True, tokenize=False) for conversation in conversations]
+
+audios = []
+for conversation in conversations:
+ for message in conversation:
+ if isinstance(message["content"], list):
+ for ele in message["content"]:
+ if ele["type"] == "audio":
+ audios.append(
+ librosa.load(
+ BytesIO(urlopen(ele['audio_url']).read()),
+ sr=processor.feature_extractor.sampling_rate)[0]
+ )
+
+inputs = processor(text=text, audios=audios, return_tensors="pt", padding=True)
+inputs['input_ids'] = inputs['input_ids'].to("cuda")
+inputs.input_ids = inputs.input_ids.to("cuda")
+
+generate_ids = model.generate(**inputs, max_length=256)
+generate_ids = generate_ids[:, inputs.input_ids.size(1):]
+
+response = processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)
+```
+
+## Qwen2AudioConfig
+
+[[autodoc]] Qwen2AudioConfig
+
+## Qwen2AudioConfig
+
+[[autodoc]] Qwen2AudioEncoderConfig
+
+## Qwen2AudioProcessor
+
+[[autodoc]] Qwen2AudioProcessor
+
+## Qwen2AudioForConditionalGeneration
+
+[[autodoc]] Qwen2AudioForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/qwen2_moe.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/qwen2_moe.md
new file mode 100644
index 0000000000000000000000000000000000000000..3a7391ca194fc5bf809a49ad0d8532337ca0b342
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/qwen2_moe.md
@@ -0,0 +1,87 @@
+
+
+# Qwen2MoE
+
+## Overview
+
+Qwen2MoE is the new model series of large language models from the Qwen team. Previously, we released the Qwen series, including Qwen-72B, Qwen-1.8B, Qwen-VL, Qwen-Audio, etc.
+
+### Model Details
+
+Qwen2MoE is a language model series including decoder language models of different model sizes. For each size, we release the base language model and the aligned chat model. Qwen2MoE has the following architectural choices:
+
+- Qwen2MoE is based on the Transformer architecture with SwiGLU activation, attention QKV bias, group query attention, mixture of sliding window attention and full attention, etc. Additionally, we have an improved tokenizer adaptive to multiple natural languages and codes.
+- Qwen2MoE employs Mixture of Experts (MoE) architecture, where the models are upcycled from dense language models. For instance, `Qwen1.5-MoE-A2.7B` is upcycled from `Qwen-1.8B`. It has 14.3B parameters in total and 2.7B activated parameters during runtime, while it achieves comparable performance with `Qwen1.5-7B`, with only 25% of the training resources.
+
+For more details refer to the [release blog post](https://qwenlm.github.io/blog/qwen-moe/).
+
+## Usage tips
+
+`Qwen1.5-MoE-A2.7B` and `Qwen1.5-MoE-A2.7B-Chat` can be found on the [Huggingface Hub](https://huggingface.co/Qwen)
+
+In the following, we demonstrate how to use `Qwen1.5-MoE-A2.7B-Chat` for the inference. Note that we have used the ChatML format for dialog, in this demo we show how to leverage `apply_chat_template` for this purpose.
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+>>> device = "cuda" # the device to load the model onto
+
+>>> model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen1.5-MoE-A2.7B-Chat", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen1.5-MoE-A2.7B-Chat")
+
+>>> prompt = "Give me a short introduction to large language model."
+
+>>> messages = [{"role": "user", "content": prompt}]
+
+>>> text = tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
+
+>>> model_inputs = tokenizer([text], return_tensors="pt").to(device)
+
+>>> generated_ids = model.generate(model_inputs.input_ids, max_new_tokens=512, do_sample=True)
+
+>>> generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(model_inputs.input_ids, generated_ids)]
+
+>>> response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+```
+
+## Qwen2MoeConfig
+
+[[autodoc]] Qwen2MoeConfig
+
+## Qwen2MoeModel
+
+[[autodoc]] Qwen2MoeModel
+ - forward
+
+## Qwen2MoeForCausalLM
+
+[[autodoc]] Qwen2MoeForCausalLM
+ - forward
+
+## Qwen2MoeForSequenceClassification
+
+[[autodoc]] Qwen2MoeForSequenceClassification
+ - forward
+
+## Qwen2MoeForTokenClassification
+
+[[autodoc]] Qwen2MoeForTokenClassification
+ - forward
+
+## Qwen2MoeForQuestionAnswering
+
+[[autodoc]] Qwen2MoeForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/qwen2_vl.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/qwen2_vl.md
new file mode 100644
index 0000000000000000000000000000000000000000..7c864b860bd8ea848c5f91e7c6ecc6ee8bdb5000
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/qwen2_vl.md
@@ -0,0 +1,330 @@
+
+
+# Qwen2-VL
+
+## Overview
+
+The [Qwen2-VL](https://qwenlm.github.io/blog/qwen2-vl/) model is a major update to [Qwen-VL](https://arxiv.org/pdf/2308.12966) from the Qwen team at Alibaba Research.
+
+The abstract from the blog is the following:
+
+*This blog introduces Qwen2-VL, an advanced version of the Qwen-VL model that has undergone significant enhancements over the past year. Key improvements include enhanced image comprehension, advanced video understanding, integrated visual agent functionality, and expanded multilingual support. The model architecture has been optimized for handling arbitrary image resolutions through Naive Dynamic Resolution support and utilizes Multimodal Rotary Position Embedding (M-ROPE) to effectively process both 1D textual and multi-dimensional visual data. This updated model demonstrates competitive performance against leading AI systems like GPT-4o and Claude 3.5 Sonnet in vision-related tasks and ranks highly among open-source models in text capabilities. These advancements make Qwen2-VL a versatile tool for various applications requiring robust multimodal processing and reasoning abilities.*
+
+
+
+ Qwen2-VL architecture. Taken from the blog post.
+
+This model was contributed by [simonJJJ](https://huggingface.co/simonJJJ).
+
+## Usage example
+
+### Single Media inference
+
+The model can accept both images and videos as input. Here's an example code for inference.
+
+```python
+
+from PIL import Image
+import requests
+import torch
+from torchvision import io
+from typing import Dict
+from transformers import Qwen2VLForConditionalGeneration, AutoTokenizer, AutoProcessor
+
+# Load the model in half-precision on the available device(s)
+model = Qwen2VLForConditionalGeneration.from_pretrained("Qwen/Qwen2-VL-7B-Instruct", device_map="auto")
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-VL-7B-Instruct")
+
+# Image
+url = "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-VL/assets/demo.jpeg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+conversation = [
+ {
+ "role":"user",
+ "content":[
+ {
+ "type":"image",
+ },
+ {
+ "type":"text",
+ "text":"Describe this image."
+ }
+ ]
+ }
+]
+
+
+# Preprocess the inputs
+text_prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+# Excepted output: '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n<|im_start|>user\n<|vision_start|><|image_pad|><|vision_end|>Describe this image.<|im_end|>\n<|im_start|>assistant\n'
+
+inputs = processor(text=[text_prompt], images=[image], padding=True, return_tensors="pt")
+inputs = inputs.to('cuda')
+
+# Inference: Generation of the output
+output_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(inputs.input_ids, output_ids)]
+output_text = processor.batch_decode(generated_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+print(output_text)
+
+# Video
+def fetch_video(ele: Dict, nframe_factor=2):
+ if isinstance(ele['video'], str):
+ def round_by_factor(number: int, factor: int) -> int:
+ return round(number / factor) * factor
+
+ video = ele["video"]
+ if video.startswith("file://"):
+ video = video[7:]
+
+ video, _, info = io.read_video(
+ video,
+ start_pts=ele.get("video_start", 0.0),
+ end_pts=ele.get("video_end", None),
+ pts_unit="sec",
+ output_format="TCHW",
+ )
+ assert not ("fps" in ele and "nframes" in ele), "Only accept either `fps` or `nframes`"
+ if "nframes" in ele:
+ nframes = round_by_factor(ele["nframes"], nframe_factor)
+ else:
+ fps = ele.get("fps", 1.0)
+ nframes = round_by_factor(video.size(0) / info["video_fps"] * fps, nframe_factor)
+ idx = torch.linspace(0, video.size(0) - 1, nframes, dtype=torch.int64)
+ return video[idx]
+
+video_info = {"type": "video", "video": "/path/to/video.mp4", "fps": 1.0}
+video = fetch_video(video_info)
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "video"},
+ {"type": "text", "text": "What happened in the video?"},
+ ],
+ }
+]
+
+# Preprocess the inputs
+text_prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+# Excepted output: '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n<|im_start|>user\n<|vision_start|><|video_pad|><|vision_end|>What happened in the video?<|im_end|>\n<|im_start|>assistant\n'
+
+inputs = processor(text=[text_prompt], videos=[video], padding=True, return_tensors="pt")
+inputs = inputs.to('cuda')
+
+# Inference: Generation of the output
+output_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(inputs.input_ids, output_ids)]
+output_text = processor.batch_decode(generated_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+print(output_text)
+```
+
+### Batch Mixed Media Inference
+
+The model can batch inputs composed of mixed samples of various types such as images, videos, and text. Here is an example.
+
+```python
+image1 = Image.open("/path/to/image1.jpg")
+image2 = Image.open("/path/to/image2.jpg")
+image3 = Image.open("/path/to/image3.jpg")
+image4 = Image.open("/path/to/image4.jpg")
+image5 = Image.open("/path/to/image5.jpg")
+video = fetch_video({
+ "type": "video",
+ "video": "/path/to/video.mp4",
+ "fps": 1.0
+})
+
+# Conversation for the first image
+conversation1 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "Describe this image."}
+ ]
+ }
+]
+
+# Conversation with two images
+conversation2 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "image"},
+ {"type": "text", "text": "What is written in the pictures?"}
+ ]
+ }
+]
+
+# Conversation with pure text
+conversation3 = [
+ {
+ "role": "user",
+ "content": "who are you?"
+ }
+]
+
+
+# Conversation with mixed midia
+conversation4 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "image"},
+ {"type": "video"},
+ {"type": "text", "text": "What are the common elements in these medias?"},
+ ],
+ }
+]
+
+conversations = [conversation1, conversation2, conversation3, conversation4]
+# Preparation for batch inference
+texts = [processor.apply_chat_template(msg, add_generation_prompt=True) for msg in conversations]
+inputs = processor(
+ text=texts,
+ images=[image1, image2, image3, image4, image5],
+ videos=[video],
+ padding=True,
+ return_tensors="pt",
+)
+inputs = inputs.to('cuda')
+
+# Batch Inference
+output_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(inputs.input_ids, output_ids)]
+output_text = processor.batch_decode(generated_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+print(output_text)
+```
+
+### Usage Tips
+
+#### Image Resolution trade-off
+
+The model supports a wide range of resolution inputs. By default, it uses the native resolution for input, but higher resolutions can enhance performance at the cost of more computation. Users can set the minimum and maximum number of pixels to achieve an optimal configuration for their needs.
+
+```python
+min_pixels = 224*224
+max_pixels = 2048*2048
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-VL-7B-Instruct", min_pixels=min_pixels, max_pixels=max_pixels)
+```
+
+In case of limited GPU RAM, one can reduce the resolution as follows:
+
+```python
+min_pixels = 256*28*28
+max_pixels = 1024*28*28
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-VL-7B-Instruct", min_pixels=min_pixels, max_pixels=max_pixels)
+```
+This ensures each image gets encoded using a number between 256-1024 tokens. The 28 comes from the fact that the model uses a patch size of 14 and a temporal patch size of 2 (14 x 2 = 28).
+
+#### Multiple Image Inputs
+
+By default, images and video content are directly included in the conversation. When handling multiple images, it's helpful to add labels to the images and videos for better reference. Users can control this behavior with the following settings:
+
+```python
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "Hello, how are you?"}
+ ]
+ },
+ {
+ "role": "assistant",
+ "content": "I'm doing well, thank you for asking. How can I assist you today?"
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Can you describe these images and video?"},
+ {"type": "image"},
+ {"type": "image"},
+ {"type": "video"},
+ {"type": "text", "text": "These are from my vacation."}
+ ]
+ },
+ {
+ "role": "assistant",
+ "content": "I'd be happy to describe the images and video for you. Could you please provide more context about your vacation?"
+ },
+ {
+ "role": "user",
+ "content": "It was a trip to the mountains. Can you see the details in the images and video?"
+ }
+]
+
+# default:
+prompt_without_id = processor.apply_chat_template(conversation, add_generation_prompt=True)
+# Excepted output: '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n<|im_start|>user\n<|vision_start|><|image_pad|><|vision_end|>Hello, how are you?<|im_end|>\n<|im_start|>assistant\nI'm doing well, thank you for asking. How can I assist you today?<|im_end|>\n<|im_start|>user\nCan you describe these images and video?<|vision_start|><|image_pad|><|vision_end|><|vision_start|><|image_pad|><|vision_end|><|vision_start|><|video_pad|><|vision_end|>These are from my vacation.<|im_end|>\n<|im_start|>assistant\nI'd be happy to describe the images and video for you. Could you please provide more context about your vacation?<|im_end|>\n<|im_start|>user\nIt was a trip to the mountains. Can you see the details in the images and video?<|im_end|>\n<|im_start|>assistant\n'
+
+
+# add ids
+prompt_with_id = processor.apply_chat_template(conversation, add_generation_prompt=True, add_vision_id=True)
+# Excepted output: '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n<|im_start|>user\nPicture 1: <|vision_start|><|image_pad|><|vision_end|>Hello, how are you?<|im_end|>\n<|im_start|>assistant\nI'm doing well, thank you for asking. How can I assist you today?<|im_end|>\n<|im_start|>user\nCan you describe these images and video?Picture 2: <|vision_start|><|image_pad|><|vision_end|>Picture 3: <|vision_start|><|image_pad|><|vision_end|>Video 1: <|vision_start|><|video_pad|><|vision_end|>These are from my vacation.<|im_end|>\n<|im_start|>assistant\nI'd be happy to describe the images and video for you. Could you please provide more context about your vacation?<|im_end|>\n<|im_start|>user\nIt was a trip to the mountains. Can you see the details in the images and video?<|im_end|>\n<|im_start|>assistant\n'
+
+```
+
+#### Flash-Attention 2 to speed up generation
+
+First, make sure to install the latest version of Flash Attention 2:
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Also, you should have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of the [flash attention repository](https://github.com/Dao-AILab/flash-attention). FlashAttention-2 can only be used when a model is loaded in `torch.float16` or `torch.bfloat16`.
+
+To load and run a model using Flash Attention-2, simply add `attn_implementation="flash_attention_2"` when loading the model as follows:
+
+```python
+from transformers import Qwen2VLForConditionalGeneration
+
+model = Qwen2VLForConditionalGeneration.from_pretrained(
+ "Qwen/Qwen2-VL-7B-Instruct",
+ torch_dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+)
+```
+
+## Qwen2VLConfig
+
+[[autodoc]] Qwen2VLConfig
+
+## Qwen2VLImageProcessor
+
+[[autodoc]] Qwen2VLImageProcessor
+ - preprocess
+
+## Qwen2VLProcessor
+
+[[autodoc]] Qwen2VLProcessor
+
+## Qwen2VLModel
+
+[[autodoc]] Qwen2VLModel
+ - forward
+
+## Qwen2VLForConditionalGeneration
+
+[[autodoc]] Qwen2VLForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/rag.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/rag.md
new file mode 100644
index 0000000000000000000000000000000000000000..1891efe742639e212c431a585aaa09326e39fc91
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/rag.md
@@ -0,0 +1,121 @@
+
+
+# RAG
+
+
+
+## Overview
+
+Retrieval-augmented generation ("RAG") models combine the powers of pretrained dense retrieval (DPR) and
+sequence-to-sequence models. RAG models retrieve documents, pass them to a seq2seq model, then marginalize to generate
+outputs. The retriever and seq2seq modules are initialized from pretrained models, and fine-tuned jointly, allowing
+both retrieval and generation to adapt to downstream tasks.
+
+It is based on the paper [Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks](https://arxiv.org/abs/2005.11401) by Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir
+Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, Douwe Kiela.
+
+The abstract from the paper is the following:
+
+*Large pre-trained language models have been shown to store factual knowledge in their parameters, and achieve
+state-of-the-art results when fine-tuned on downstream NLP tasks. However, their ability to access and precisely
+manipulate knowledge is still limited, and hence on knowledge-intensive tasks, their performance lags behind
+task-specific architectures. Additionally, providing provenance for their decisions and updating their world knowledge
+remain open research problems. Pre-trained models with a differentiable access mechanism to explicit nonparametric
+memory can overcome this issue, but have so far been only investigated for extractive downstream tasks. We explore a
+general-purpose fine-tuning recipe for retrieval-augmented generation (RAG) — models which combine pre-trained
+parametric and non-parametric memory for language generation. We introduce RAG models where the parametric memory is a
+pre-trained seq2seq model and the non-parametric memory is a dense vector index of Wikipedia, accessed with a
+pre-trained neural retriever. We compare two RAG formulations, one which conditions on the same retrieved passages
+across the whole generated sequence, the other can use different passages per token. We fine-tune and evaluate our
+models on a wide range of knowledge-intensive NLP tasks and set the state-of-the-art on three open domain QA tasks,
+outperforming parametric seq2seq models and task-specific retrieve-and-extract architectures. For language generation
+tasks, we find that RAG models generate more specific, diverse and factual language than a state-of-the-art
+parametric-only seq2seq baseline.*
+
+This model was contributed by [ola13](https://huggingface.co/ola13).
+
+## Usage tips
+
+Retrieval-augmented generation ("RAG") models combine the powers of pretrained dense retrieval (DPR) and Seq2Seq models.
+RAG models retrieve docs, pass them to a seq2seq model, then marginalize to generate outputs. The retriever and seq2seq
+modules are initialized from pretrained models, and fine-tuned jointly, allowing both retrieval and generation to adapt
+to downstream tasks.
+
+## RagConfig
+
+[[autodoc]] RagConfig
+
+## RagTokenizer
+
+[[autodoc]] RagTokenizer
+
+## Rag specific outputs
+
+[[autodoc]] models.rag.modeling_rag.RetrievAugLMMarginOutput
+
+[[autodoc]] models.rag.modeling_rag.RetrievAugLMOutput
+
+## RagRetriever
+
+[[autodoc]] RagRetriever
+
+
+
+
+## RagModel
+
+[[autodoc]] RagModel
+ - forward
+
+## RagSequenceForGeneration
+
+[[autodoc]] RagSequenceForGeneration
+ - forward
+ - generate
+
+## RagTokenForGeneration
+
+[[autodoc]] RagTokenForGeneration
+ - forward
+ - generate
+
+
+
+
+## TFRagModel
+
+[[autodoc]] TFRagModel
+ - call
+
+## TFRagSequenceForGeneration
+
+[[autodoc]] TFRagSequenceForGeneration
+ - call
+ - generate
+
+## TFRagTokenForGeneration
+
+[[autodoc]] TFRagTokenForGeneration
+ - call
+ - generate
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/realm.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/realm.md
new file mode 100644
index 0000000000000000000000000000000000000000..558e83c08b06a60b794bde8a1f9cce351bd43a5a
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/realm.md
@@ -0,0 +1,97 @@
+
+
+# REALM
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The REALM model was proposed in [REALM: Retrieval-Augmented Language Model Pre-Training](https://arxiv.org/abs/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang. It's a
+retrieval-augmented language model that firstly retrieves documents from a textual knowledge corpus and then
+utilizes retrieved documents to process question answering tasks.
+
+The abstract from the paper is the following:
+
+*Language model pre-training has been shown to capture a surprising amount of world knowledge, crucial for NLP tasks
+such as question answering. However, this knowledge is stored implicitly in the parameters of a neural network,
+requiring ever-larger networks to cover more facts. To capture knowledge in a more modular and interpretable way, we
+augment language model pre-training with a latent knowledge retriever, which allows the model to retrieve and attend
+over documents from a large corpus such as Wikipedia, used during pre-training, fine-tuning and inference. For the
+first time, we show how to pre-train such a knowledge retriever in an unsupervised manner, using masked language
+modeling as the learning signal and backpropagating through a retrieval step that considers millions of documents. We
+demonstrate the effectiveness of Retrieval-Augmented Language Model pre-training (REALM) by fine-tuning on the
+challenging task of Open-domain Question Answering (Open-QA). We compare against state-of-the-art models for both
+explicit and implicit knowledge storage on three popular Open-QA benchmarks, and find that we outperform all previous
+methods by a significant margin (4-16% absolute accuracy), while also providing qualitative benefits such as
+interpretability and modularity.*
+
+This model was contributed by [qqaatw](https://huggingface.co/qqaatw). The original code can be found
+[here](https://github.com/google-research/language/tree/master/language/realm).
+
+## RealmConfig
+
+[[autodoc]] RealmConfig
+
+## RealmTokenizer
+
+[[autodoc]] RealmTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+ - batch_encode_candidates
+
+## RealmTokenizerFast
+
+[[autodoc]] RealmTokenizerFast
+ - batch_encode_candidates
+
+## RealmRetriever
+
+[[autodoc]] RealmRetriever
+
+## RealmEmbedder
+
+[[autodoc]] RealmEmbedder
+ - forward
+
+## RealmScorer
+
+[[autodoc]] RealmScorer
+ - forward
+
+## RealmKnowledgeAugEncoder
+
+[[autodoc]] RealmKnowledgeAugEncoder
+ - forward
+
+## RealmReader
+
+[[autodoc]] RealmReader
+ - forward
+
+## RealmForOpenQA
+
+[[autodoc]] RealmForOpenQA
+ - block_embedding_to
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/recurrent_gemma.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/recurrent_gemma.md
new file mode 100644
index 0000000000000000000000000000000000000000..ceee799159fcf40f18136328b67fa934addff674
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/recurrent_gemma.md
@@ -0,0 +1,48 @@
+
+
+# RecurrentGemma
+
+## Overview
+
+The Recurrent Gemma model was proposed in [RecurrentGemma: Moving Past Transformers for Efficient Open Language Models](https://storage.googleapis.com/deepmind-media/gemma/recurrentgemma-report.pdf) by the Griffin, RLHF and Gemma Teams of Google.
+
+The abstract from the paper is the following:
+
+*We introduce RecurrentGemma, an open language model which uses Google’s novel Griffin architecture. Griffin combines linear recurrences with local attention to achieve excellent performance on language. It has a fixed-sized state, which reduces memory use and enables efficient inference on long sequences. We provide a pre-trained model with 2B non-embedding parameters, and an instruction tuned variant. Both models achieve comparable performance to Gemma-2B despite being trained on fewer tokens.*
+
+Tips:
+
+- The original checkpoints can be converted using the conversion script [`src/transformers/models/recurrent_gemma/convert_recurrent_gemma_weights_to_hf.py`](https://github.com/huggingface/transformers/blob/main/src/transformers/models/recurrent_gemma/convert_recurrent_gemma_to_hf.py).
+
+This model was contributed by [Arthur Zucker](https://huggingface.co/ArthurZ). The original code can be found [here](https://github.com/google-deepmind/recurrentgemma).
+
+
+## RecurrentGemmaConfig
+
+[[autodoc]] RecurrentGemmaConfig
+
+
+## RecurrentGemmaModel
+
+[[autodoc]] RecurrentGemmaModel
+ - forward
+
+## RecurrentGemmaForCausalLM
+
+[[autodoc]] RecurrentGemmaForCausalLM
+ - forward
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/reformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/reformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..c78b1bbb8333d437b58c225d189051e75ada807a
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/reformer.md
@@ -0,0 +1,199 @@
+
+
+# Reformer
+
+
+
+## Overview
+
+The Reformer model was proposed in the paper [Reformer: The Efficient Transformer](https://arxiv.org/abs/2001.04451.pdf) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
+
+The abstract from the paper is the following:
+
+*Large Transformer models routinely achieve state-of-the-art results on a number of tasks but training these models can
+be prohibitively costly, especially on long sequences. We introduce two techniques to improve the efficiency of
+Transformers. For one, we replace dot-product attention by one that uses locality-sensitive hashing, changing its
+complexity from O(L^2) to O(Llog(L)), where L is the length of the sequence. Furthermore, we use reversible residual
+layers instead of the standard residuals, which allows storing activations only once in the training process instead of
+N times, where N is the number of layers. The resulting model, the Reformer, performs on par with Transformer models
+while being much more memory-efficient and much faster on long sequences.*
+
+This model was contributed by [patrickvonplaten](https://huggingface.co/patrickvonplaten). The Authors' code can be
+found [here](https://github.com/google/trax/tree/master/trax/models/reformer).
+
+## Usage tips
+
+- Reformer does **not** work with *torch.nn.DataParallel* due to a bug in PyTorch, see [issue #36035](https://github.com/pytorch/pytorch/issues/36035).
+- Use Axial position encoding (see below for more details). It’s a mechanism to avoid having a huge positional encoding matrix (when the sequence length is very big) by factorizing it into smaller matrices.
+- Replace traditional attention by LSH (local-sensitive hashing) attention (see below for more details). It’s a technique to avoid computing the full product query-key in the attention layers.
+- Avoid storing the intermediate results of each layer by using reversible transformer layers to obtain them during the backward pass (subtracting the residuals from the input of the next layer gives them back) or recomputing them for results inside a given layer (less efficient than storing them but saves memory).
+- Compute the feedforward operations by chunks and not on the whole batch.
+
+### Axial Positional Encodings
+
+Axial Positional Encodings were first implemented in Google's [trax library](https://github.com/google/trax/blob/4d99ad4965bab1deba227539758d59f0df0fef48/trax/layers/research/position_encodings.py#L29)
+and developed by the authors of this model's paper. In models that are treating very long input sequences, the
+conventional position id encodings store an embeddings vector of size \\(d\\) being the `config.hidden_size` for
+every position \\(i, \ldots, n_s\\), with \\(n_s\\) being `config.max_embedding_size`. This means that having
+a sequence length of \\(n_s = 2^{19} \approx 0.5M\\) and a `config.hidden_size` of \\(d = 2^{10} \approx 1000\\)
+would result in a position encoding matrix:
+
+$$X_{i,j}, \text{ with } i \in \left[1,\ldots, d\right] \text{ and } j \in \left[1,\ldots, n_s\right]$$
+
+which alone has over 500M parameters to store. Axial positional encodings factorize \\(X_{i,j}\\) into two matrices:
+
+$$X^{1}_{i,j}, \text{ with } i \in \left[1,\ldots, d^1\right] \text{ and } j \in \left[1,\ldots, n_s^1\right]$$
+
+and
+
+$$X^{2}_{i,j}, \text{ with } i \in \left[1,\ldots, d^2\right] \text{ and } j \in \left[1,\ldots, n_s^2\right]$$
+
+with:
+
+$$d = d^1 + d^2 \text{ and } n_s = n_s^1 \times n_s^2 .$$
+
+Therefore the following holds:
+
+$$X_{i,j} = \begin{cases}
+X^{1}_{i, k}, & \text{if }\ i < d^1 \text{ with } k = j \mod n_s^1 \\
+X^{2}_{i - d^1, l}, & \text{if } i \ge d^1 \text{ with } l = \lfloor\frac{j}{n_s^1}\rfloor
+\end{cases}$$
+
+Intuitively, this means that a position embedding vector \\(x_j \in \mathbb{R}^{d}\\) is now the composition of two
+factorized embedding vectors: \\(x^1_{k, l} + x^2_{l, k}\\), where as the `config.max_embedding_size` dimension
+\\(j\\) is factorized into \\(k \text{ and } l\\). This design ensures that each position embedding vector
+\\(x_j\\) is unique.
+
+Using the above example again, axial position encoding with \\(d^1 = 2^9, d^2 = 2^9, n_s^1 = 2^9, n_s^2 = 2^{10}\\)
+can drastically reduced the number of parameters from 500 000 000 to \\(2^{18} + 2^{19} \approx 780 000\\) parameters, this means 85% less memory usage.
+
+In practice, the parameter `config.axial_pos_embds_dim` is set to a tuple \\((d^1, d^2)\\) which sum has to be
+equal to `config.hidden_size` and `config.axial_pos_shape` is set to a tuple \\((n_s^1, n_s^2)\\) which
+product has to be equal to `config.max_embedding_size`, which during training has to be equal to the *sequence
+length* of the `input_ids`.
+
+
+### LSH Self Attention
+
+In Locality sensitive hashing (LSH) self attention the key and query projection weights are tied. Therefore, the key
+query embedding vectors are also tied. LSH self attention uses the locality sensitive hashing mechanism proposed in
+[Practical and Optimal LSH for Angular Distance](https://arxiv.org/abs/1509.02897) to assign each of the tied key
+query embedding vectors to one of `config.num_buckets` possible buckets. The premise is that the more "similar"
+key query embedding vectors (in terms of *cosine similarity*) are to each other, the more likely they are assigned to
+the same bucket.
+
+The accuracy of the LSH mechanism can be improved by increasing `config.num_hashes` or directly the argument
+`num_hashes` of the forward function so that the output of the LSH self attention better approximates the output
+of the "normal" full self attention. The buckets are then sorted and chunked into query key embedding vector chunks
+each of length `config.lsh_chunk_length`. For each chunk, the query embedding vectors attend to its key vectors
+(which are tied to themselves) and to the key embedding vectors of `config.lsh_num_chunks_before` previous
+neighboring chunks and `config.lsh_num_chunks_after` following neighboring chunks.
+
+For more information, see the [original Paper](https://arxiv.org/abs/2001.04451) or this great [blog post](https://www.pragmatic.ml/reformer-deep-dive/).
+
+Note that `config.num_buckets` can also be factorized into a list \\((n_{\text{buckets}}^1,
+n_{\text{buckets}}^2)\\). This way instead of assigning the query key embedding vectors to one of \\((1,\ldots,
+n_{\text{buckets}})\\) they are assigned to one of \\((1-1,\ldots, n_{\text{buckets}}^1-1, \ldots,
+1-n_{\text{buckets}}^2, \ldots, n_{\text{buckets}}^1-n_{\text{buckets}}^2)\\). This is crucial for very long sequences to
+save memory.
+
+When training a model from scratch, it is recommended to leave `config.num_buckets=None`, so that depending on the
+sequence length a good value for `num_buckets` is calculated on the fly. This value will then automatically be
+saved in the config and should be reused for inference.
+
+Using LSH self attention, the memory and time complexity of the query-key matmul operation can be reduced from
+\\(\mathcal{O}(n_s \times n_s)\\) to \\(\mathcal{O}(n_s \times \log(n_s))\\), which usually represents the memory
+and time bottleneck in a transformer model, with \\(n_s\\) being the sequence length.
+
+
+### Local Self Attention
+
+Local self attention is essentially a "normal" self attention layer with key, query and value projections, but is
+chunked so that in each chunk of length `config.local_chunk_length` the query embedding vectors only attends to
+the key embedding vectors in its chunk and to the key embedding vectors of `config.local_num_chunks_before`
+previous neighboring chunks and `config.local_num_chunks_after` following neighboring chunks.
+
+Using Local self attention, the memory and time complexity of the query-key matmul operation can be reduced from
+\\(\mathcal{O}(n_s \times n_s)\\) to \\(\mathcal{O}(n_s \times \log(n_s))\\), which usually represents the memory
+and time bottleneck in a transformer model, with \\(n_s\\) being the sequence length.
+
+
+### Training
+
+During training, we must ensure that the sequence length is set to a value that can be divided by the least common
+multiple of `config.lsh_chunk_length` and `config.local_chunk_length` and that the parameters of the Axial
+Positional Encodings are correctly set as described above. Reformer is very memory efficient so that the model can
+easily be trained on sequences as long as 64000 tokens.
+
+For training, the [`ReformerModelWithLMHead`] should be used as follows:
+
+```python
+input_ids = tokenizer.encode("This is a sentence from the training data", return_tensors="pt")
+loss = model(input_ids, labels=input_ids)[0]
+```
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+
+## ReformerConfig
+
+[[autodoc]] ReformerConfig
+
+## ReformerTokenizer
+
+[[autodoc]] ReformerTokenizer
+ - save_vocabulary
+
+## ReformerTokenizerFast
+
+[[autodoc]] ReformerTokenizerFast
+
+## ReformerModel
+
+[[autodoc]] ReformerModel
+ - forward
+
+## ReformerModelWithLMHead
+
+[[autodoc]] ReformerModelWithLMHead
+ - forward
+
+## ReformerForMaskedLM
+
+[[autodoc]] ReformerForMaskedLM
+ - forward
+
+## ReformerForSequenceClassification
+
+[[autodoc]] ReformerForSequenceClassification
+ - forward
+
+## ReformerForQuestionAnswering
+
+[[autodoc]] ReformerForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/regnet.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/regnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..acd833c77c2da935f2e11a91f3cfd2bb2c5173cc
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/regnet.md
@@ -0,0 +1,90 @@
+
+
+# RegNet
+
+## Overview
+
+The RegNet model was proposed in [Designing Network Design Spaces](https://arxiv.org/abs/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
+
+The authors design search spaces to perform Neural Architecture Search (NAS). They first start from a high dimensional search space and iteratively reduce the search space by empirically applying constraints based on the best-performing models sampled by the current search space.
+
+The abstract from the paper is the following:
+
+*In this work, we present a new network design paradigm. Our goal is to help advance the understanding of network design and discover design principles that generalize across settings. Instead of focusing on designing individual network instances, we design network design spaces that parametrize populations of networks. The overall process is analogous to classic manual design of networks, but elevated to the design space level. Using our methodology we explore the structure aspect of network design and arrive at a low-dimensional design space consisting of simple, regular networks that we call RegNet. The core insight of the RegNet parametrization is surprisingly simple: widths and depths of good networks can be explained by a quantized linear function. We analyze the RegNet design space and arrive at interesting findings that do not match the current practice of network design. The RegNet design space provides simple and fast networks that work well across a wide range of flop regimes. Under comparable training settings and flops, the RegNet models outperform the popular EfficientNet models while being up to 5x faster on GPUs.*
+
+This model was contributed by [Francesco](https://huggingface.co/Francesco). The TensorFlow version of the model
+was contributed by [sayakpaul](https://huggingface.co/sayakpaul) and [ariG23498](https://huggingface.co/ariG23498).
+The original code can be found [here](https://github.com/facebookresearch/pycls).
+
+The huge 10B model from [Self-supervised Pretraining of Visual Features in the Wild](https://arxiv.org/abs/2103.01988),
+trained on one billion Instagram images, is available on the [hub](https://huggingface.co/facebook/regnet-y-10b-seer)
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with RegNet.
+
+
+
+- [`RegNetForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## RegNetConfig
+
+[[autodoc]] RegNetConfig
+
+
+
+
+## RegNetModel
+
+[[autodoc]] RegNetModel
+ - forward
+
+## RegNetForImageClassification
+
+[[autodoc]] RegNetForImageClassification
+ - forward
+
+
+
+
+## TFRegNetModel
+
+[[autodoc]] TFRegNetModel
+ - call
+
+## TFRegNetForImageClassification
+
+[[autodoc]] TFRegNetForImageClassification
+ - call
+
+
+
+
+## FlaxRegNetModel
+
+[[autodoc]] FlaxRegNetModel
+ - __call__
+
+## FlaxRegNetForImageClassification
+
+[[autodoc]] FlaxRegNetForImageClassification
+ - __call__
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/rembert.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/rembert.md
new file mode 100644
index 0000000000000000000000000000000000000000..b755d3423060cafca9ee7a849e6fed1238756373
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/rembert.md
@@ -0,0 +1,150 @@
+
+
+# RemBERT
+
+## Overview
+
+The RemBERT model was proposed in [Rethinking Embedding Coupling in Pre-trained Language Models](https://arxiv.org/abs/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, Melvin Johnson, Sebastian Ruder.
+
+The abstract from the paper is the following:
+
+*We re-evaluate the standard practice of sharing weights between input and output embeddings in state-of-the-art
+pre-trained language models. We show that decoupled embeddings provide increased modeling flexibility, allowing us to
+significantly improve the efficiency of parameter allocation in the input embedding of multilingual models. By
+reallocating the input embedding parameters in the Transformer layers, we achieve dramatically better performance on
+standard natural language understanding tasks with the same number of parameters during fine-tuning. We also show that
+allocating additional capacity to the output embedding provides benefits to the model that persist through the
+fine-tuning stage even though the output embedding is discarded after pre-training. Our analysis shows that larger
+output embeddings prevent the model's last layers from overspecializing to the pre-training task and encourage
+Transformer representations to be more general and more transferable to other tasks and languages. Harnessing these
+findings, we are able to train models that achieve strong performance on the XTREME benchmark without increasing the
+number of parameters at the fine-tuning stage.*
+
+## Usage tips
+
+For fine-tuning, RemBERT can be thought of as a bigger version of mBERT with an ALBERT-like factorization of the
+embedding layer. The embeddings are not tied in pre-training, in contrast with BERT, which enables smaller input
+embeddings (preserved during fine-tuning) and bigger output embeddings (discarded at fine-tuning). The tokenizer is
+also similar to the Albert one rather than the BERT one.
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## RemBertConfig
+
+[[autodoc]] RemBertConfig
+
+## RemBertTokenizer
+
+[[autodoc]] RemBertTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## RemBertTokenizerFast
+
+[[autodoc]] RemBertTokenizerFast
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+
+
+
+## RemBertModel
+
+[[autodoc]] RemBertModel
+ - forward
+
+## RemBertForCausalLM
+
+[[autodoc]] RemBertForCausalLM
+ - forward
+
+## RemBertForMaskedLM
+
+[[autodoc]] RemBertForMaskedLM
+ - forward
+
+## RemBertForSequenceClassification
+
+[[autodoc]] RemBertForSequenceClassification
+ - forward
+
+## RemBertForMultipleChoice
+
+[[autodoc]] RemBertForMultipleChoice
+ - forward
+
+## RemBertForTokenClassification
+
+[[autodoc]] RemBertForTokenClassification
+ - forward
+
+## RemBertForQuestionAnswering
+
+[[autodoc]] RemBertForQuestionAnswering
+ - forward
+
+
+
+
+## TFRemBertModel
+
+[[autodoc]] TFRemBertModel
+ - call
+
+## TFRemBertForMaskedLM
+
+[[autodoc]] TFRemBertForMaskedLM
+ - call
+
+## TFRemBertForCausalLM
+
+[[autodoc]] TFRemBertForCausalLM
+ - call
+
+## TFRemBertForSequenceClassification
+
+[[autodoc]] TFRemBertForSequenceClassification
+ - call
+
+## TFRemBertForMultipleChoice
+
+[[autodoc]] TFRemBertForMultipleChoice
+ - call
+
+## TFRemBertForTokenClassification
+
+[[autodoc]] TFRemBertForTokenClassification
+ - call
+
+## TFRemBertForQuestionAnswering
+
+[[autodoc]] TFRemBertForQuestionAnswering
+ - call
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/resnet.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/resnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..b959266512f50206764983fa75ea9690c6a78b83
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/resnet.md
@@ -0,0 +1,91 @@
+
+
+# ResNet
+
+## Overview
+
+The ResNet model was proposed in [Deep Residual Learning for Image Recognition](https://arxiv.org/abs/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren and Jian Sun. Our implementation follows the small changes made by [Nvidia](https://catalog.ngc.nvidia.com/orgs/nvidia/resources/resnet_50_v1_5_for_pytorch), we apply the `stride=2` for downsampling in bottleneck's `3x3` conv and not in the first `1x1`. This is generally known as "ResNet v1.5".
+
+ResNet introduced residual connections, they allow to train networks with an unseen number of layers (up to 1000). ResNet won the 2015 ILSVRC & COCO competition, one important milestone in deep computer vision.
+
+The abstract from the paper is the following:
+
+*Deeper neural networks are more difficult to train. We present a residual learning framework to ease the training of networks that are substantially deeper than those used previously. We explicitly reformulate the layers as learning residual functions with reference to the layer inputs, instead of learning unreferenced functions. We provide comprehensive empirical evidence showing that these residual networks are easier to optimize, and can gain accuracy from considerably increased depth. On the ImageNet dataset we evaluate residual nets with a depth of up to 152 layers---8x deeper than VGG nets but still having lower complexity. An ensemble of these residual nets achieves 3.57% error on the ImageNet test set. This result won the 1st place on the ILSVRC 2015 classification task. We also present analysis on CIFAR-10 with 100 and 1000 layers.
+The depth of representations is of central importance for many visual recognition tasks. Solely due to our extremely deep representations, we obtain a 28% relative improvement on the COCO object detection dataset. Deep residual nets are foundations of our submissions to ILSVRC & COCO 2015 competitions, where we also won the 1st places on the tasks of ImageNet detection, ImageNet localization, COCO detection, and COCO segmentation.*
+
+The figure below illustrates the architecture of ResNet. Taken from the [original paper](https://arxiv.org/abs/1512.03385).
+
+
+
+This model was contributed by [Francesco](https://huggingface.co/Francesco). The TensorFlow version of this model was added by [amyeroberts](https://huggingface.co/amyeroberts). The original code can be found [here](https://github.com/KaimingHe/deep-residual-networks).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with ResNet.
+
+
+
+- [`ResNetForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## ResNetConfig
+
+[[autodoc]] ResNetConfig
+
+
+
+
+## ResNetModel
+
+[[autodoc]] ResNetModel
+ - forward
+
+## ResNetForImageClassification
+
+[[autodoc]] ResNetForImageClassification
+ - forward
+
+
+
+
+## TFResNetModel
+
+[[autodoc]] TFResNetModel
+ - call
+
+## TFResNetForImageClassification
+
+[[autodoc]] TFResNetForImageClassification
+ - call
+
+
+
+
+## FlaxResNetModel
+
+[[autodoc]] FlaxResNetModel
+ - __call__
+
+## FlaxResNetForImageClassification
+
+[[autodoc]] FlaxResNetForImageClassification
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/retribert.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/retribert.md
new file mode 100644
index 0000000000000000000000000000000000000000..ab29ac966fe19fc1d07cfa3d40c847ab81903b55
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/retribert.md
@@ -0,0 +1,53 @@
+
+
+# RetriBERT
+
+
+
+This model is in maintenance mode only, so we won't accept any new PRs changing its code.
+
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.30.0.
+You can do so by running the following command: `pip install -U transformers==4.30.0`.
+
+
+
+## Overview
+
+The RetriBERT model was proposed in the blog post [Explain Anything Like I'm Five: A Model for Open Domain Long Form
+Question Answering](https://yjernite.github.io/lfqa.html). RetriBERT is a small model that uses either a single or
+pair of BERT encoders with lower-dimension projection for dense semantic indexing of text.
+
+This model was contributed by [yjernite](https://huggingface.co/yjernite). Code to train and use the model can be
+found [here](https://github.com/huggingface/transformers/tree/main/examples/research-projects/distillation).
+
+
+## RetriBertConfig
+
+[[autodoc]] RetriBertConfig
+
+## RetriBertTokenizer
+
+[[autodoc]] RetriBertTokenizer
+
+## RetriBertTokenizerFast
+
+[[autodoc]] RetriBertTokenizerFast
+
+## RetriBertModel
+
+[[autodoc]] RetriBertModel
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/roberta-prelayernorm.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/roberta-prelayernorm.md
new file mode 100644
index 0000000000000000000000000000000000000000..f748e273e8f80ecf4f6e36be8c80c8568832493d
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/roberta-prelayernorm.md
@@ -0,0 +1,164 @@
+
+
+# RoBERTa-PreLayerNorm
+
+## Overview
+
+The RoBERTa-PreLayerNorm model was proposed in [fairseq: A Fast, Extensible Toolkit for Sequence Modeling](https://arxiv.org/abs/1904.01038) by Myle Ott, Sergey Edunov, Alexei Baevski, Angela Fan, Sam Gross, Nathan Ng, David Grangier, Michael Auli.
+It is identical to using the `--encoder-normalize-before` flag in [fairseq](https://fairseq.readthedocs.io/).
+
+The abstract from the paper is the following:
+
+*fairseq is an open-source sequence modeling toolkit that allows researchers and developers to train custom models for translation, summarization, language modeling, and other text generation tasks. The toolkit is based on PyTorch and supports distributed training across multiple GPUs and machines. We also support fast mixed-precision training and inference on modern GPUs.*
+
+This model was contributed by [andreasmaden](https://huggingface.co/andreasmadsen).
+The original code can be found [here](https://github.com/princeton-nlp/DinkyTrain).
+
+## Usage tips
+
+- The implementation is the same as [Roberta](roberta) except instead of using _Add and Norm_ it does _Norm and Add_. _Add_ and _Norm_ refers to the Addition and LayerNormalization as described in [Attention Is All You Need](https://arxiv.org/abs/1706.03762).
+- This is identical to using the `--encoder-normalize-before` flag in [fairseq](https://fairseq.readthedocs.io/).
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## RobertaPreLayerNormConfig
+
+[[autodoc]] RobertaPreLayerNormConfig
+
+
+
+
+## RobertaPreLayerNormModel
+
+[[autodoc]] RobertaPreLayerNormModel
+ - forward
+
+## RobertaPreLayerNormForCausalLM
+
+[[autodoc]] RobertaPreLayerNormForCausalLM
+ - forward
+
+## RobertaPreLayerNormForMaskedLM
+
+[[autodoc]] RobertaPreLayerNormForMaskedLM
+ - forward
+
+## RobertaPreLayerNormForSequenceClassification
+
+[[autodoc]] RobertaPreLayerNormForSequenceClassification
+ - forward
+
+## RobertaPreLayerNormForMultipleChoice
+
+[[autodoc]] RobertaPreLayerNormForMultipleChoice
+ - forward
+
+## RobertaPreLayerNormForTokenClassification
+
+[[autodoc]] RobertaPreLayerNormForTokenClassification
+ - forward
+
+## RobertaPreLayerNormForQuestionAnswering
+
+[[autodoc]] RobertaPreLayerNormForQuestionAnswering
+ - forward
+
+
+
+
+## TFRobertaPreLayerNormModel
+
+[[autodoc]] TFRobertaPreLayerNormModel
+ - call
+
+## TFRobertaPreLayerNormForCausalLM
+
+[[autodoc]] TFRobertaPreLayerNormForCausalLM
+ - call
+
+## TFRobertaPreLayerNormForMaskedLM
+
+[[autodoc]] TFRobertaPreLayerNormForMaskedLM
+ - call
+
+## TFRobertaPreLayerNormForSequenceClassification
+
+[[autodoc]] TFRobertaPreLayerNormForSequenceClassification
+ - call
+
+## TFRobertaPreLayerNormForMultipleChoice
+
+[[autodoc]] TFRobertaPreLayerNormForMultipleChoice
+ - call
+
+## TFRobertaPreLayerNormForTokenClassification
+
+[[autodoc]] TFRobertaPreLayerNormForTokenClassification
+ - call
+
+## TFRobertaPreLayerNormForQuestionAnswering
+
+[[autodoc]] TFRobertaPreLayerNormForQuestionAnswering
+ - call
+
+
+
+
+## FlaxRobertaPreLayerNormModel
+
+[[autodoc]] FlaxRobertaPreLayerNormModel
+ - __call__
+
+## FlaxRobertaPreLayerNormForCausalLM
+
+[[autodoc]] FlaxRobertaPreLayerNormForCausalLM
+ - __call__
+
+## FlaxRobertaPreLayerNormForMaskedLM
+
+[[autodoc]] FlaxRobertaPreLayerNormForMaskedLM
+ - __call__
+
+## FlaxRobertaPreLayerNormForSequenceClassification
+
+[[autodoc]] FlaxRobertaPreLayerNormForSequenceClassification
+ - __call__
+
+## FlaxRobertaPreLayerNormForMultipleChoice
+
+[[autodoc]] FlaxRobertaPreLayerNormForMultipleChoice
+ - __call__
+
+## FlaxRobertaPreLayerNormForTokenClassification
+
+[[autodoc]] FlaxRobertaPreLayerNormForTokenClassification
+ - __call__
+
+## FlaxRobertaPreLayerNormForQuestionAnswering
+
+[[autodoc]] FlaxRobertaPreLayerNormForQuestionAnswering
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/roberta.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/roberta.md
new file mode 100644
index 0000000000000000000000000000000000000000..2a1843d8885abecef49c61fc5d0ea6388f17b8c9
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/roberta.md
@@ -0,0 +1,245 @@
+
+
+# RoBERTa
+
+
+
+## Overview
+
+The RoBERTa model was proposed in [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://arxiv.org/abs/1907.11692) by Yinhan Liu, [Myle Ott](https://huggingface.co/myleott), Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer
+Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov. It is based on Google's BERT model released in 2018.
+
+It builds on BERT and modifies key hyperparameters, removing the next-sentence pretraining objective and training with
+much larger mini-batches and learning rates.
+
+The abstract from the paper is the following:
+
+*Language model pretraining has led to significant performance gains but careful comparison between different
+approaches is challenging. Training is computationally expensive, often done on private datasets of different sizes,
+and, as we will show, hyperparameter choices have significant impact on the final results. We present a replication
+study of BERT pretraining (Devlin et al., 2019) that carefully measures the impact of many key hyperparameters and
+training data size. We find that BERT was significantly undertrained, and can match or exceed the performance of every
+model published after it. Our best model achieves state-of-the-art results on GLUE, RACE and SQuAD. These results
+highlight the importance of previously overlooked design choices, and raise questions about the source of recently
+reported improvements. We release our models and code.*
+
+This model was contributed by [julien-c](https://huggingface.co/julien-c). The original code can be found [here](https://github.com/pytorch/fairseq/tree/master/examples/roberta).
+
+## Usage tips
+
+- This implementation is the same as [`BertModel`] with a minor tweak to the embeddings, as well as a setup
+ for RoBERTa pretrained models.
+- RoBERTa has the same architecture as BERT but uses a byte-level BPE as a tokenizer (same as GPT-2) and uses a
+ different pretraining scheme.
+- RoBERTa doesn't have `token_type_ids`, so you don't need to indicate which token belongs to which segment. Just
+ separate your segments with the separation token `tokenizer.sep_token` (or ``).
+- RoBERTa is similar to BERT but with better pretraining techniques:
+
+ * Dynamic masking: tokens are masked differently at each epoch, whereas BERT does it once and for all.
+ * Sentence packing: Sentences are packed together to reach 512 tokens (so the sentences are in an order that may span several documents).
+ * Larger batches: Training uses larger batches.
+ * Byte-level BPE vocabulary: Uses BPE with bytes as a subunit instead of characters, accommodating Unicode characters.
+- [CamemBERT](camembert) is a wrapper around RoBERTa. Refer to its model page for usage examples.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with RoBERTa. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- A blog on [Getting Started with Sentiment Analysis on Twitter](https://huggingface.co/blog/sentiment-analysis-twitter) using RoBERTa and the [Inference API](https://huggingface.co/inference-api).
+- A blog on [Opinion Classification with Kili and Hugging Face AutoTrain](https://huggingface.co/blog/opinion-classification-with-kili) using RoBERTa.
+- A notebook on how to [finetune RoBERTa for sentiment analysis](https://colab.research.google.com/github/DhavalTaunk08/NLP_scripts/blob/master/sentiment_analysis_using_roberta.ipynb). 🌎
+- [`RobertaForSequenceClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification.ipynb).
+- [`TFRobertaForSequenceClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/text-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification-tf.ipynb).
+- [`FlaxRobertaForSequenceClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/flax/text-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification_flax.ipynb).
+- [Text classification task guide](../tasks/sequence_classification)
+
+
+
+- [`RobertaForTokenClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/token-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification.ipynb).
+- [`TFRobertaForTokenClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/token-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification-tf.ipynb).
+- [`FlaxRobertaForTokenClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/flax/token-classification).
+- [Token classification](https://huggingface.co/course/chapter7/2?fw=pt) chapter of the 🤗 Hugging Face Course.
+- [Token classification task guide](../tasks/token_classification)
+
+
+
+- A blog on [How to train a new language model from scratch using Transformers and Tokenizers](https://huggingface.co/blog/how-to-train) with RoBERTa.
+- [`RobertaForMaskedLM`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/language-modeling#robertabertdistilbert-and-masked-language-modeling) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb).
+- [`TFRobertaForMaskedLM`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/language-modeling#run_mlmpy) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb).
+- [`FlaxRobertaForMaskedLM`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/flax/language-modeling#masked-language-modeling) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/masked_language_modeling_flax.ipynb).
+- [Masked language modeling](https://huggingface.co/course/chapter7/3?fw=pt) chapter of the 🤗 Hugging Face Course.
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+
+
+
+- A blog on [Accelerated Inference with Optimum and Transformers Pipelines](https://huggingface.co/blog/optimum-inference) with RoBERTa for question answering.
+- [`RobertaForQuestionAnswering`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb).
+- [`TFRobertaForQuestionAnswering`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/question-answering) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering-tf.ipynb).
+- [`FlaxRobertaForQuestionAnswering`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/flax/question-answering).
+- [Question answering](https://huggingface.co/course/chapter7/7?fw=pt) chapter of the 🤗 Hugging Face Course.
+- [Question answering task guide](../tasks/question_answering)
+
+**Multiple choice**
+- [`RobertaForMultipleChoice`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/multiple-choice) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice.ipynb).
+- [`TFRobertaForMultipleChoice`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/multiple-choice) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice-tf.ipynb).
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## RobertaConfig
+
+[[autodoc]] RobertaConfig
+
+## RobertaTokenizer
+
+[[autodoc]] RobertaTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## RobertaTokenizerFast
+
+[[autodoc]] RobertaTokenizerFast
+ - build_inputs_with_special_tokens
+
+
+
+
+## RobertaModel
+
+[[autodoc]] RobertaModel
+ - forward
+
+## RobertaForCausalLM
+
+[[autodoc]] RobertaForCausalLM
+ - forward
+
+## RobertaForMaskedLM
+
+[[autodoc]] RobertaForMaskedLM
+ - forward
+
+## RobertaForSequenceClassification
+
+[[autodoc]] RobertaForSequenceClassification
+ - forward
+
+## RobertaForMultipleChoice
+
+[[autodoc]] RobertaForMultipleChoice
+ - forward
+
+## RobertaForTokenClassification
+
+[[autodoc]] RobertaForTokenClassification
+ - forward
+
+## RobertaForQuestionAnswering
+
+[[autodoc]] RobertaForQuestionAnswering
+ - forward
+
+
+
+
+## TFRobertaModel
+
+[[autodoc]] TFRobertaModel
+ - call
+
+## TFRobertaForCausalLM
+
+[[autodoc]] TFRobertaForCausalLM
+ - call
+
+## TFRobertaForMaskedLM
+
+[[autodoc]] TFRobertaForMaskedLM
+ - call
+
+## TFRobertaForSequenceClassification
+
+[[autodoc]] TFRobertaForSequenceClassification
+ - call
+
+## TFRobertaForMultipleChoice
+
+[[autodoc]] TFRobertaForMultipleChoice
+ - call
+
+## TFRobertaForTokenClassification
+
+[[autodoc]] TFRobertaForTokenClassification
+ - call
+
+## TFRobertaForQuestionAnswering
+
+[[autodoc]] TFRobertaForQuestionAnswering
+ - call
+
+
+
+
+## FlaxRobertaModel
+
+[[autodoc]] FlaxRobertaModel
+ - __call__
+
+## FlaxRobertaForCausalLM
+
+[[autodoc]] FlaxRobertaForCausalLM
+ - __call__
+
+## FlaxRobertaForMaskedLM
+
+[[autodoc]] FlaxRobertaForMaskedLM
+ - __call__
+
+## FlaxRobertaForSequenceClassification
+
+[[autodoc]] FlaxRobertaForSequenceClassification
+ - __call__
+
+## FlaxRobertaForMultipleChoice
+
+[[autodoc]] FlaxRobertaForMultipleChoice
+ - __call__
+
+## FlaxRobertaForTokenClassification
+
+[[autodoc]] FlaxRobertaForTokenClassification
+ - __call__
+
+## FlaxRobertaForQuestionAnswering
+
+[[autodoc]] FlaxRobertaForQuestionAnswering
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/roc_bert.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/roc_bert.md
new file mode 100644
index 0000000000000000000000000000000000000000..30fadd5c2c10d82da4a01aa9f79ccb8cf2f70cea
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/roc_bert.md
@@ -0,0 +1,98 @@
+
+
+# RoCBert
+
+## Overview
+
+The RoCBert model was proposed in [RoCBert: Robust Chinese Bert with Multimodal Contrastive Pretraining](https://aclanthology.org/2022.acl-long.65.pdf) by HuiSu, WeiweiShi, XiaoyuShen, XiaoZhou, TuoJi, JiaruiFang, JieZhou.
+It's a pretrained Chinese language model that is robust under various forms of adversarial attacks.
+
+The abstract from the paper is the following:
+
+*Large-scale pretrained language models have achieved SOTA results on NLP tasks. However, they have been shown
+vulnerable to adversarial attacks especially for logographic languages like Chinese. In this work, we propose
+ROCBERT: a pretrained Chinese Bert that is robust to various forms of adversarial attacks like word perturbation,
+synonyms, typos, etc. It is pretrained with the contrastive learning objective which maximizes the label consistency
+under different synthesized adversarial examples. The model takes as input multimodal information including the
+semantic, phonetic and visual features. We show all these features are important to the model robustness since the
+attack can be performed in all the three forms. Across 5 Chinese NLU tasks, ROCBERT outperforms strong baselines under
+three blackbox adversarial algorithms without sacrificing the performance on clean testset. It also performs the best
+in the toxic content detection task under human-made attacks.*
+
+This model was contributed by [weiweishi](https://huggingface.co/weiweishi).
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## RoCBertConfig
+
+[[autodoc]] RoCBertConfig
+ - all
+
+## RoCBertTokenizer
+
+[[autodoc]] RoCBertTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## RoCBertModel
+
+[[autodoc]] RoCBertModel
+ - forward
+
+## RoCBertForPreTraining
+
+[[autodoc]] RoCBertForPreTraining
+ - forward
+
+## RoCBertForCausalLM
+
+[[autodoc]] RoCBertForCausalLM
+ - forward
+
+## RoCBertForMaskedLM
+
+[[autodoc]] RoCBertForMaskedLM
+ - forward
+
+## RoCBertForSequenceClassification
+
+[[autodoc]] transformers.RoCBertForSequenceClassification
+ - forward
+
+## RoCBertForMultipleChoice
+
+[[autodoc]] transformers.RoCBertForMultipleChoice
+ - forward
+
+## RoCBertForTokenClassification
+
+[[autodoc]] transformers.RoCBertForTokenClassification
+ - forward
+
+## RoCBertForQuestionAnswering
+
+[[autodoc]] RoCBertForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/roformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/roformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..5d8f146c43fdd30aaa5f022acd5972e3e6ac7b46
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/roformer.md
@@ -0,0 +1,178 @@
+
+
+# RoFormer
+
+## Overview
+
+The RoFormer model was proposed in [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/pdf/2104.09864v1.pdf) by Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu.
+
+The abstract from the paper is the following:
+
+*Position encoding in transformer architecture provides supervision for dependency modeling between elements at
+different positions in the sequence. We investigate various methods to encode positional information in
+transformer-based language models and propose a novel implementation named Rotary Position Embedding(RoPE). The
+proposed RoPE encodes absolute positional information with rotation matrix and naturally incorporates explicit relative
+position dependency in self-attention formulation. Notably, RoPE comes with valuable properties such as flexibility of
+being expand to any sequence lengths, decaying inter-token dependency with increasing relative distances, and
+capability of equipping the linear self-attention with relative position encoding. As a result, the enhanced
+transformer with rotary position embedding, or RoFormer, achieves superior performance in tasks with long texts. We
+release the theoretical analysis along with some preliminary experiment results on Chinese data. The undergoing
+experiment for English benchmark will soon be updated.*
+
+This model was contributed by [junnyu](https://huggingface.co/junnyu). The original code can be found [here](https://github.com/ZhuiyiTechnology/roformer).
+
+## Usage tips
+RoFormer is a BERT-like autoencoding model with rotary position embeddings. Rotary position embeddings have shown
+improved performance on classification tasks with long texts.
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## RoFormerConfig
+
+[[autodoc]] RoFormerConfig
+
+## RoFormerTokenizer
+
+[[autodoc]] RoFormerTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## RoFormerTokenizerFast
+
+[[autodoc]] RoFormerTokenizerFast
+ - build_inputs_with_special_tokens
+
+
+
+
+## RoFormerModel
+
+[[autodoc]] RoFormerModel
+ - forward
+
+## RoFormerForCausalLM
+
+[[autodoc]] RoFormerForCausalLM
+ - forward
+
+## RoFormerForMaskedLM
+
+[[autodoc]] RoFormerForMaskedLM
+ - forward
+
+## RoFormerForSequenceClassification
+
+[[autodoc]] RoFormerForSequenceClassification
+ - forward
+
+## RoFormerForMultipleChoice
+
+[[autodoc]] RoFormerForMultipleChoice
+ - forward
+
+## RoFormerForTokenClassification
+
+[[autodoc]] RoFormerForTokenClassification
+ - forward
+
+## RoFormerForQuestionAnswering
+
+[[autodoc]] RoFormerForQuestionAnswering
+ - forward
+
+
+
+
+## TFRoFormerModel
+
+[[autodoc]] TFRoFormerModel
+ - call
+
+## TFRoFormerForMaskedLM
+
+[[autodoc]] TFRoFormerForMaskedLM
+ - call
+
+## TFRoFormerForCausalLM
+
+[[autodoc]] TFRoFormerForCausalLM
+ - call
+
+## TFRoFormerForSequenceClassification
+
+[[autodoc]] TFRoFormerForSequenceClassification
+ - call
+
+## TFRoFormerForMultipleChoice
+
+[[autodoc]] TFRoFormerForMultipleChoice
+ - call
+
+## TFRoFormerForTokenClassification
+
+[[autodoc]] TFRoFormerForTokenClassification
+ - call
+
+## TFRoFormerForQuestionAnswering
+
+[[autodoc]] TFRoFormerForQuestionAnswering
+ - call
+
+
+
+
+## FlaxRoFormerModel
+
+[[autodoc]] FlaxRoFormerModel
+ - __call__
+
+## FlaxRoFormerForMaskedLM
+
+[[autodoc]] FlaxRoFormerForMaskedLM
+ - __call__
+
+## FlaxRoFormerForSequenceClassification
+
+[[autodoc]] FlaxRoFormerForSequenceClassification
+ - __call__
+
+## FlaxRoFormerForMultipleChoice
+
+[[autodoc]] FlaxRoFormerForMultipleChoice
+ - __call__
+
+## FlaxRoFormerForTokenClassification
+
+[[autodoc]] FlaxRoFormerForTokenClassification
+ - __call__
+
+## FlaxRoFormerForQuestionAnswering
+
+[[autodoc]] FlaxRoFormerForQuestionAnswering
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/rt_detr.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/rt_detr.md
new file mode 100644
index 0000000000000000000000000000000000000000..6a1545e123297c2e2a189dc9fb8e1abfdf4dd609
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/rt_detr.md
@@ -0,0 +1,117 @@
+
+
+# RT-DETR
+
+## Overview
+
+
+The RT-DETR model was proposed in [DETRs Beat YOLOs on Real-time Object Detection](https://arxiv.org/abs/2304.08069) by Wenyu Lv, Yian Zhao, Shangliang Xu, Jinman Wei, Guanzhong Wang, Cheng Cui, Yuning Du, Qingqing Dang, Yi Liu.
+
+RT-DETR is an object detection model that stands for "Real-Time DEtection Transformer." This model is designed to perform object detection tasks with a focus on achieving real-time performance while maintaining high accuracy. Leveraging the transformer architecture, which has gained significant popularity in various fields of deep learning, RT-DETR processes images to identify and locate multiple objects within them.
+
+The abstract from the paper is the following:
+
+*Recently, end-to-end transformer-based detectors (DETRs) have achieved remarkable performance. However, the issue of the high computational cost of DETRs has not been effectively addressed, limiting their practical application and preventing them from fully exploiting the benefits of no post-processing, such as non-maximum suppression (NMS). In this paper, we first analyze the influence of NMS in modern real-time object detectors on inference speed, and establish an end-to-end speed benchmark. To avoid the inference delay caused by NMS, we propose a Real-Time DEtection TRansformer (RT-DETR), the first real-time end-to-end object detector to our best knowledge. Specifically, we design an efficient hybrid encoder to efficiently process multi-scale features by decoupling the intra-scale interaction and cross-scale fusion, and propose IoU-aware query selection to improve the initialization of object queries. In addition, our proposed detector supports flexibly adjustment of the inference speed by using different decoder layers without the need for retraining, which facilitates the practical application of real-time object detectors. Our RT-DETR-L achieves 53.0% AP on COCO val2017 and 114 FPS on T4 GPU, while RT-DETR-X achieves 54.8% AP and 74 FPS, outperforming all YOLO detectors of the same scale in both speed and accuracy. Furthermore, our RT-DETR-R50 achieves 53.1% AP and 108 FPS, outperforming DINO-Deformable-DETR-R50 by 2.2% AP in accuracy and by about 21 times in FPS.*
+
+
+
+ RT-DETR performance relative to YOLO models. Taken from the original paper.
+
+The model version was contributed by [rafaelpadilla](https://huggingface.co/rafaelpadilla) and [sangbumchoi](https://github.com/SangbumChoi). The original code can be found [here](https://github.com/lyuwenyu/RT-DETR/).
+
+
+## Usage tips
+
+Initially, an image is processed using a pre-trained convolutional neural network, specifically a Resnet-D variant as referenced in the original code. This network extracts features from the final three layers of the architecture. Following this, a hybrid encoder is employed to convert the multi-scale features into a sequential array of image features. Then, a decoder, equipped with auxiliary prediction heads is used to refine the object queries. This process facilitates the direct generation of bounding boxes, eliminating the need for any additional post-processing to acquire the logits and coordinates for the bounding boxes.
+
+```py
+>>> import torch
+>>> import requests
+
+>>> from PIL import Image
+>>> from transformers import RTDetrForObjectDetection, RTDetrImageProcessor
+
+>>> url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> image_processor = RTDetrImageProcessor.from_pretrained("PekingU/rtdetr_r50vd")
+>>> model = RTDetrForObjectDetection.from_pretrained("PekingU/rtdetr_r50vd")
+
+>>> inputs = image_processor(images=image, return_tensors="pt")
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> results = image_processor.post_process_object_detection(outputs, target_sizes=torch.tensor([(image.height, image.width)]), threshold=0.3)
+
+>>> for result in results:
+... for score, label_id, box in zip(result["scores"], result["labels"], result["boxes"]):
+... score, label = score.item(), label_id.item()
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"{model.config.id2label[label]}: {score:.2f} {box}")
+sofa: 0.97 [0.14, 0.38, 640.13, 476.21]
+cat: 0.96 [343.38, 24.28, 640.14, 371.5]
+cat: 0.96 [13.23, 54.18, 318.98, 472.22]
+remote: 0.95 [40.11, 73.44, 175.96, 118.48]
+remote: 0.92 [333.73, 76.58, 369.97, 186.99]
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with RT-DETR.
+
+
+
+- Scripts for finetuning [`RTDetrForObjectDetection`] with [`Trainer`] or [Accelerate](https://huggingface.co/docs/accelerate/index) can be found [here](https://github.com/huggingface/transformers/tree/main/examples/pytorch/object-detection).
+- See also: [Object detection task guide](../tasks/object_detection).
+- Notebooks regarding inference and fine-tuning RT-DETR on a custom dataset can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/RT-DETR). 🌎
+
+## RTDetrConfig
+
+[[autodoc]] RTDetrConfig
+
+## RTDetrResNetConfig
+
+[[autodoc]] RTDetrResNetConfig
+
+## RTDetrImageProcessor
+
+[[autodoc]] RTDetrImageProcessor
+ - preprocess
+ - post_process_object_detection
+
+## RTDetrImageProcessorFast
+
+[[autodoc]] RTDetrImageProcessorFast
+ - preprocess
+ - post_process_object_detection
+
+## RTDetrModel
+
+[[autodoc]] RTDetrModel
+ - forward
+
+## RTDetrForObjectDetection
+
+[[autodoc]] RTDetrForObjectDetection
+ - forward
+
+## RTDetrResNetBackbone
+
+[[autodoc]] RTDetrResNetBackbone
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/rwkv.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/rwkv.md
new file mode 100644
index 0000000000000000000000000000000000000000..1acb173060216ba2b2fcebbff3462a729dfa10fb
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/rwkv.md
@@ -0,0 +1,150 @@
+
+
+# RWKV
+
+## Overview
+
+The RWKV model was proposed in [this repo](https://github.com/BlinkDL/RWKV-LM)
+
+It suggests a tweak in the traditional Transformer attention to make it linear. This way, the model can be used as recurrent network: passing inputs for timestamp 0 and timestamp 1 together is the same as passing inputs at timestamp 0, then inputs at timestamp 1 along with the state of timestamp 0 (see example below).
+
+This can be more efficient than a regular Transformer and can deal with sentence of any length (even if the model uses a fixed context length for training).
+
+This model was contributed by [sgugger](https://huggingface.co/sgugger).
+The original code can be found [here](https://github.com/BlinkDL/RWKV-LM).
+
+## Usage example
+
+```py
+import torch
+from transformers import AutoTokenizer, RwkvConfig, RwkvModel
+
+model = RwkvModel.from_pretrained("sgugger/rwkv-430M-pile")
+tokenizer = AutoTokenizer.from_pretrained("sgugger/rwkv-430M-pile")
+
+inputs = tokenizer("This is an example.", return_tensors="pt")
+# Feed everything to the model
+outputs = model(inputs["input_ids"])
+output_whole = outputs.last_hidden_state
+
+outputs = model(inputs["input_ids"][:, :2])
+output_one = outputs.last_hidden_state
+
+# Using the state computed on the first inputs, we will get the same output
+outputs = model(inputs["input_ids"][:, 2:], state=outputs.state)
+output_two = outputs.last_hidden_state
+
+torch.allclose(torch.cat([output_one, output_two], dim=1), output_whole, atol=1e-5)
+```
+
+If you want to make sure the model stops generating when `'\n\n'` is detected, we recommend using the following stopping criteria:
+
+```python
+from transformers import StoppingCriteria
+
+class RwkvStoppingCriteria(StoppingCriteria):
+ def __init__(self, eos_sequence = [187,187], eos_token_id = 537):
+ self.eos_sequence = eos_sequence
+ self.eos_token_id = eos_token_id
+
+ def __call__(self, input_ids: torch.LongTensor, scores: torch.FloatTensor, **kwargs) -> bool:
+ last_2_ids = input_ids[:,-2:].tolist()
+ return self.eos_sequence in last_2_ids
+
+
+output = model.generate(inputs["input_ids"], max_new_tokens=64, stopping_criteria = [RwkvStoppingCriteria()])
+```
+
+## RwkvConfig
+
+[[autodoc]] RwkvConfig
+
+## RwkvModel
+
+[[autodoc]] RwkvModel
+ - forward
+
+## RwkvLMHeadModel
+
+[[autodoc]] RwkvForCausalLM
+ - forward
+
+## Rwkv attention and the recurrent formulas
+
+In a traditional auto-regressive Transformer, attention is written as
+
+$$O = \hbox{softmax}(QK^{T} / \sqrt{d}) V$$
+
+with \\(Q\\), \\(K\\) and \\(V\\) are matrices of shape `seq_len x hidden_size` named query, key and value (they are actually bigger matrices with a batch dimension and an attention head dimension but we're only interested in the last two, which is where the matrix product is taken, so for the sake of simplicity we only consider those two). The product \\(QK^{T}\\) then has shape `seq_len x seq_len` and we can take the matrix product with \\(V\\) to get the output \\(O\\) of the same shape as the others.
+
+Replacing the softmax by its value gives:
+
+$$O_{i} = \frac{\sum_{j=1}^{i} e^{Q_{i} K_{j}^{T} / \sqrt{d}} V_{j}}{\sum_{j=1}^{i} e^{Q_{i} K_{j}^{T} / \sqrt{d}}}$$
+
+Note that the entries in \\(QK^{T}\\) corresponding to \\(j > i\\) are masked (the sum stops at j) because the attention is not allowed to look at future tokens (only past ones).
+
+In comparison, the RWKV attention is given by
+
+$$O_{i} = \sigma(R_{i}) \frac{\sum_{j=1}^{i} e^{W_{i-j} + K_{j}} V_{j}}{\sum_{j=1}^{i} e^{W_{i-j} + K_{j}}}$$
+
+where \\(R\\) is a new matrix called receptance by the author, \\(K\\) and \\(V\\) are still the key and value (\\(\sigma\\) here is the sigmoid function). \\(W\\) is a new vector that represents the position of the token and is given by
+
+$$W_{0} = u \hbox{ and } W_{k} = (k-1)w \hbox{ for } k \geq 1$$
+
+with \\(u\\) and \\(w\\) learnable parameters called in the code `time_first` and `time_decay` respectively. The numerator and denominator can both be expressed recursively. Naming them \\(N_{i}\\) and \\(D_{i}\\) we have:
+
+$$N_{i} = e^{u + K_{i}} V_{i} + \hat{N}_{i} \hbox{ where } \hat{N}_{i} = e^{K_{i-1}} V_{i-1} + e^{w + K_{i-2}} V_{i-2} \cdots + e^{(i-2)w + K_{1}} V_{1}$$
+
+so \\(\hat{N}_{i}\\) (called `numerator_state` in the code) satisfies
+
+$$\hat{N}_{0} = 0 \hbox{ and } \hat{N}_{j+1} = e^{K_{j}} V_{j} + e^{w} \hat{N}_{j}$$
+
+and
+
+$$D_{i} = e^{u + K_{i}} + \hat{D}_{i} \hbox{ where } \hat{D}_{i} = e^{K_{i-1}} + e^{w + K_{i-2}} \cdots + e^{(i-2)w + K_{1}}$$
+
+so \\(\hat{D}_{i}\\) (called `denominator_state` in the code) satisfies
+
+$$\hat{D}_{0} = 0 \hbox{ and } \hat{D}_{j+1} = e^{K_{j}} + e^{w} \hat{D}_{j}$$
+
+The actual recurrent formula used are a tiny bit more complex, as for numerical stability we don't want to compute exponentials of big numbers. Usually the softmax is not computed as is, but the exponential of the maximum term is divided of the numerator and denominator:
+
+$$\frac{e^{x_{i}}}{\sum_{j=1}^{n} e^{x_{j}}} = \frac{e^{x_{i} - M}}{\sum_{j=1}^{n} e^{x_{j} - M}}$$
+
+with \\(M\\) the maximum of all \\(x_{j}\\). So here on top of saving the numerator state (\\(\hat{N}\\)) and the denominator state (\\(\hat{D}\\)) we also keep track of the maximum of all terms encountered in the exponentials. So we actually use
+
+$$\tilde{N}_{i} = e^{-M_{i}} \hat{N}_{i} \hbox{ and } \tilde{D}_{i} = e^{-M_{i}} \hat{D}_{i}$$
+
+defined by the following recurrent formulas:
+
+$$\tilde{N}_{0} = 0 \hbox{ and } \tilde{N}_{j+1} = e^{K_{j} - q} V_{j} + e^{w + M_{j} - q} \tilde{N}_{j} \hbox{ where } q = \max(K_{j}, w + M_{j})$$
+
+and
+
+$$\tilde{D}_{0} = 0 \hbox{ and } \tilde{D}_{j+1} = e^{K_{j} - q} + e^{w + M_{j} - q} \tilde{D}_{j} \hbox{ where } q = \max(K_{j}, w + M_{j})$$
+
+and \\(M_{j+1} = q\\). With those, we can then compute
+
+$$N_{i} = e^{u + K_{i} - q} V_{i} + e^{M_{i}} \tilde{N}_{i} \hbox{ where } q = \max(u + K_{i}, M_{i})$$
+
+and
+
+$$D_{i} = e^{u + K_{i} - q} + e^{M_{i}} \tilde{D}_{i} \hbox{ where } q = \max(u + K_{i}, M_{i})$$
+
+which finally gives us
+
+$$O_{i} = \sigma(R_{i}) \frac{N_{i}}{D_{i}}$$
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/sam.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/sam.md
new file mode 100644
index 0000000000000000000000000000000000000000..f45b08c2c23540c27bcaf15b9d4d834237e62b3a
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/sam.md
@@ -0,0 +1,156 @@
+
+
+# SAM
+
+## Overview
+
+SAM (Segment Anything Model) was proposed in [Segment Anything](https://arxiv.org/pdf/2304.02643v1.pdf) by Alexander Kirillov, Eric Mintun, Nikhila Ravi, Hanzi Mao, Chloe Rolland, Laura Gustafson, Tete Xiao, Spencer Whitehead, Alex Berg, Wan-Yen Lo, Piotr Dollar, Ross Girshick.
+
+The model can be used to predict segmentation masks of any object of interest given an input image.
+
+
+
+The abstract from the paper is the following:
+
+*We introduce the Segment Anything (SA) project: a new task, model, and dataset for image segmentation. Using our efficient model in a data collection loop, we built the largest segmentation dataset to date (by far), with over 1 billion masks on 11M licensed and privacy respecting images. The model is designed and trained to be promptable, so it can transfer zero-shot to new image distributions and tasks. We evaluate its capabilities on numerous tasks and find that its zero-shot performance is impressive -- often competitive with or even superior to prior fully supervised results. We are releasing the Segment Anything Model (SAM) and corresponding dataset (SA-1B) of 1B masks and 11M images at [https://segment-anything.com](https://segment-anything.com) to foster research into foundation models for computer vision.*
+
+Tips:
+
+- The model predicts binary masks that states the presence or not of the object of interest given an image.
+- The model predicts much better results if input 2D points and/or input bounding boxes are provided
+- You can prompt multiple points for the same image, and predict a single mask.
+- Fine-tuning the model is not supported yet
+- According to the paper, textual input should be also supported. However, at this time of writing this seems not to be supported according to [the official repository](https://github.com/facebookresearch/segment-anything/issues/4#issuecomment-1497626844).
+
+
+This model was contributed by [ybelkada](https://huggingface.co/ybelkada) and [ArthurZ](https://huggingface.co/ArthurZ).
+The original code can be found [here](https://github.com/facebookresearch/segment-anything).
+
+Below is an example on how to run mask generation given an image and a 2D point:
+
+```python
+import torch
+from PIL import Image
+import requests
+from transformers import SamModel, SamProcessor
+
+device = "cuda" if torch.cuda.is_available() else "cpu"
+model = SamModel.from_pretrained("facebook/sam-vit-huge").to(device)
+processor = SamProcessor.from_pretrained("facebook/sam-vit-huge")
+
+img_url = "https://huggingface.co/ybelkada/segment-anything/resolve/main/assets/car.png"
+raw_image = Image.open(requests.get(img_url, stream=True).raw).convert("RGB")
+input_points = [[[450, 600]]] # 2D location of a window in the image
+
+inputs = processor(raw_image, input_points=input_points, return_tensors="pt").to(device)
+with torch.no_grad():
+ outputs = model(**inputs)
+
+masks = processor.image_processor.post_process_masks(
+ outputs.pred_masks.cpu(), inputs["original_sizes"].cpu(), inputs["reshaped_input_sizes"].cpu()
+)
+scores = outputs.iou_scores
+```
+
+You can also process your own masks alongside the input images in the processor to be passed to the model.
+
+```python
+import torch
+from PIL import Image
+import requests
+from transformers import SamModel, SamProcessor
+
+device = "cuda" if torch.cuda.is_available() else "cpu"
+model = SamModel.from_pretrained("facebook/sam-vit-huge").to(device)
+processor = SamProcessor.from_pretrained("facebook/sam-vit-huge")
+
+img_url = "https://huggingface.co/ybelkada/segment-anything/resolve/main/assets/car.png"
+raw_image = Image.open(requests.get(img_url, stream=True).raw).convert("RGB")
+mask_url = "https://huggingface.co/ybelkada/segment-anything/resolve/main/assets/car.png"
+segmentation_map = Image.open(requests.get(mask_url, stream=True).raw).convert("1")
+input_points = [[[450, 600]]] # 2D location of a window in the image
+
+inputs = processor(raw_image, input_points=input_points, segmentation_maps=segmentation_map, return_tensors="pt").to(device)
+with torch.no_grad():
+ outputs = model(**inputs)
+
+masks = processor.image_processor.post_process_masks(
+ outputs.pred_masks.cpu(), inputs["original_sizes"].cpu(), inputs["reshaped_input_sizes"].cpu()
+)
+scores = outputs.iou_scores
+```
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with SAM.
+
+- [Demo notebook](https://github.com/huggingface/notebooks/blob/main/examples/segment_anything.ipynb) for using the model.
+- [Demo notebook](https://github.com/huggingface/notebooks/blob/main/examples/automatic_mask_generation.ipynb) for using the automatic mask generation pipeline.
+- [Demo notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/SAM/Run_inference_with_MedSAM_using_HuggingFace_Transformers.ipynb) for inference with MedSAM, a fine-tuned version of SAM on the medical domain. 🌎
+- [Demo notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/SAM/Fine_tune_SAM_(segment_anything)_on_a_custom_dataset.ipynb) for fine-tuning the model on custom data. 🌎
+
+## SlimSAM
+
+SlimSAM, a pruned version of SAM, was proposed in [0.1% Data Makes Segment Anything Slim](https://arxiv.org/abs/2312.05284) by Zigeng Chen et al. SlimSAM reduces the size of the SAM models considerably while maintaining the same performance.
+
+Checkpoints can be found on the [hub](https://huggingface.co/models?other=slimsam), and they can be used as a drop-in replacement of SAM.
+
+## Grounded SAM
+
+One can combine [Grounding DINO](grounding-dino) with SAM for text-based mask generation as introduced in [Grounded SAM: Assembling Open-World Models for Diverse Visual Tasks](https://arxiv.org/abs/2401.14159). You can refer to this [demo notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/Grounding%20DINO/GroundingDINO_with_Segment_Anything.ipynb) 🌍 for details.
+
+
+
+ Grounded SAM overview. Taken from the original repository.
+
+## SamConfig
+
+[[autodoc]] SamConfig
+
+## SamVisionConfig
+
+[[autodoc]] SamVisionConfig
+
+## SamMaskDecoderConfig
+
+[[autodoc]] SamMaskDecoderConfig
+
+## SamPromptEncoderConfig
+
+[[autodoc]] SamPromptEncoderConfig
+
+
+## SamProcessor
+
+[[autodoc]] SamProcessor
+
+
+## SamImageProcessor
+
+[[autodoc]] SamImageProcessor
+
+
+## SamModel
+
+[[autodoc]] SamModel
+ - forward
+
+
+## TFSamModel
+
+[[autodoc]] TFSamModel
+ - call
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/seamless_m4t.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/seamless_m4t.md
new file mode 100644
index 0000000000000000000000000000000000000000..e820e6c92563b0df84393568135e3f318be98c85
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/seamless_m4t.md
@@ -0,0 +1,220 @@
+
+
+# SeamlessM4T
+
+## Overview
+
+The SeamlessM4T model was proposed in [SeamlessM4T — Massively Multilingual & Multimodal Machine Translation](https://dl.fbaipublicfiles.com/seamless/seamless_m4t_paper.pdf) by the Seamless Communication team from Meta AI.
+
+This is the **version 1** release of the model. For the updated **version 2** release, refer to the [Seamless M4T v2 docs](https://huggingface.co/docs/transformers/main/model_doc/seamless_m4t_v2).
+
+SeamlessM4T is a collection of models designed to provide high quality translation, allowing people from different linguistic communities to communicate effortlessly through speech and text.
+
+SeamlessM4T enables multiple tasks without relying on separate models:
+
+- Speech-to-speech translation (S2ST)
+- Speech-to-text translation (S2TT)
+- Text-to-speech translation (T2ST)
+- Text-to-text translation (T2TT)
+- Automatic speech recognition (ASR)
+
+[`SeamlessM4TModel`] can perform all the above tasks, but each task also has its own dedicated sub-model.
+
+The abstract from the paper is the following:
+
+*What does it take to create the Babel Fish, a tool that can help individuals translate speech between any two languages? While recent breakthroughs in text-based models have pushed machine translation coverage beyond 200 languages, unified speech-to-speech translation models have yet to achieve similar strides. More specifically, conventional speech-to-speech translation systems rely on cascaded systems that perform translation progressively, putting high-performing unified systems out of reach. To address these gaps, we introduce SeamlessM4T, a single model that supports speech-to-speech translation, speech-to-text translation, text-to-speech translation, text-to-text translation, and automatic speech recognition for up to 100 languages. To build this, we used 1 million hours of open speech audio data to learn self-supervised speech representations with w2v-BERT 2.0. Subsequently, we created a multimodal corpus of automatically aligned speech translations. Filtered and combined with human-labeled and pseudo-labeled data, we developed the first multilingual system capable of translating from and into English for both speech and text. On FLEURS, SeamlessM4T sets a new standard for translations into multiple target languages, achieving an improvement of 20% BLEU over the previous SOTA in direct speech-to-text translation. Compared to strong cascaded models, SeamlessM4T improves the quality of into-English translation by 1.3 BLEU points in speech-to-text and by 2.6 ASR-BLEU points in speech-to-speech. Tested for robustness, our system performs better against background noises and speaker variations in speech-to-text tasks compared to the current SOTA model. Critically, we evaluated SeamlessM4T on gender bias and added toxicity to assess translation safety. Finally, all contributions in this work are open-sourced and accessible at https://github.com/facebookresearch/seamless_communication*
+
+## Usage
+
+First, load the processor and a checkpoint of the model:
+
+```python
+>>> from transformers import AutoProcessor, SeamlessM4TModel
+
+>>> processor = AutoProcessor.from_pretrained("facebook/hf-seamless-m4t-medium")
+>>> model = SeamlessM4TModel.from_pretrained("facebook/hf-seamless-m4t-medium")
+```
+
+You can seamlessly use this model on text or on audio, to generated either translated text or translated audio.
+
+Here is how to use the processor to process text and audio:
+
+```python
+>>> # let's load an audio sample from an Arabic speech corpus
+>>> from datasets import load_dataset
+>>> dataset = load_dataset("arabic_speech_corpus", split="test", streaming=True)
+>>> audio_sample = next(iter(dataset))["audio"]
+
+>>> # now, process it
+>>> audio_inputs = processor(audios=audio_sample["array"], return_tensors="pt")
+
+>>> # now, process some English test as well
+>>> text_inputs = processor(text = "Hello, my dog is cute", src_lang="eng", return_tensors="pt")
+```
+
+
+### Speech
+
+[`SeamlessM4TModel`] can *seamlessly* generate text or speech with few or no changes. Let's target Russian voice translation:
+
+```python
+>>> audio_array_from_text = model.generate(**text_inputs, tgt_lang="rus")[0].cpu().numpy().squeeze()
+>>> audio_array_from_audio = model.generate(**audio_inputs, tgt_lang="rus")[0].cpu().numpy().squeeze()
+```
+
+With basically the same code, I've translated English text and Arabic speech to Russian speech samples.
+
+### Text
+
+Similarly, you can generate translated text from audio files or from text with the same model. You only have to pass `generate_speech=False` to [`SeamlessM4TModel.generate`].
+This time, let's translate to French.
+
+```python
+>>> # from audio
+>>> output_tokens = model.generate(**audio_inputs, tgt_lang="fra", generate_speech=False)
+>>> translated_text_from_audio = processor.decode(output_tokens[0].tolist()[0], skip_special_tokens=True)
+
+>>> # from text
+>>> output_tokens = model.generate(**text_inputs, tgt_lang="fra", generate_speech=False)
+>>> translated_text_from_text = processor.decode(output_tokens[0].tolist()[0], skip_special_tokens=True)
+```
+
+### Tips
+
+
+#### 1. Use dedicated models
+
+[`SeamlessM4TModel`] is transformers top level model to generate speech and text, but you can also use dedicated models that perform the task without additional components, thus reducing the memory footprint.
+For example, you can replace the audio-to-audio generation snippet with the model dedicated to the S2ST task, the rest is exactly the same code:
+
+```python
+>>> from transformers import SeamlessM4TForSpeechToSpeech
+>>> model = SeamlessM4TForSpeechToSpeech.from_pretrained("facebook/hf-seamless-m4t-medium")
+```
+
+Or you can replace the text-to-text generation snippet with the model dedicated to the T2TT task, you only have to remove `generate_speech=False`.
+
+```python
+>>> from transformers import SeamlessM4TForTextToText
+>>> model = SeamlessM4TForTextToText.from_pretrained("facebook/hf-seamless-m4t-medium")
+```
+
+Feel free to try out [`SeamlessM4TForSpeechToText`] and [`SeamlessM4TForTextToSpeech`] as well.
+
+#### 2. Change the speaker identity
+
+You have the possibility to change the speaker used for speech synthesis with the `spkr_id` argument. Some `spkr_id` works better than other for some languages!
+
+#### 3. Change the generation strategy
+
+You can use different [generation strategies](./generation_strategies) for speech and text generation, e.g `.generate(input_ids=input_ids, text_num_beams=4, speech_do_sample=True)` which will successively perform beam-search decoding on the text model, and multinomial sampling on the speech model.
+
+#### 4. Generate speech and text at the same time
+
+Use `return_intermediate_token_ids=True` with [`SeamlessM4TModel`] to return both speech and text !
+
+## Model architecture
+
+
+SeamlessM4T features a versatile architecture that smoothly handles the sequential generation of text and speech. This setup comprises two sequence-to-sequence (seq2seq) models. The first model translates the input modality into translated text, while the second model generates speech tokens, known as "unit tokens," from the translated text.
+
+Each modality has its own dedicated encoder with a unique architecture. Additionally, for speech output, a vocoder inspired by the [HiFi-GAN](https://arxiv.org/abs/2010.05646) architecture is placed on top of the second seq2seq model.
+
+Here's how the generation process works:
+
+- Input text or speech is processed through its specific encoder.
+- A decoder creates text tokens in the desired language.
+- If speech generation is required, the second seq2seq model, following a standard encoder-decoder structure, generates unit tokens.
+- These unit tokens are then passed through the final vocoder to produce the actual speech.
+
+
+This model was contributed by [ylacombe](https://huggingface.co/ylacombe). The original code can be found [here](https://github.com/facebookresearch/seamless_communication).
+
+## SeamlessM4TModel
+
+[[autodoc]] SeamlessM4TModel
+ - generate
+
+
+## SeamlessM4TForTextToSpeech
+
+[[autodoc]] SeamlessM4TForTextToSpeech
+ - generate
+
+
+## SeamlessM4TForSpeechToSpeech
+
+[[autodoc]] SeamlessM4TForSpeechToSpeech
+ - generate
+
+
+## SeamlessM4TForTextToText
+
+[[autodoc]] transformers.SeamlessM4TForTextToText
+ - forward
+ - generate
+
+## SeamlessM4TForSpeechToText
+
+[[autodoc]] transformers.SeamlessM4TForSpeechToText
+ - forward
+ - generate
+
+## SeamlessM4TConfig
+
+[[autodoc]] SeamlessM4TConfig
+
+
+## SeamlessM4TTokenizer
+
+[[autodoc]] SeamlessM4TTokenizer
+ - __call__
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+
+## SeamlessM4TTokenizerFast
+
+[[autodoc]] SeamlessM4TTokenizerFast
+ - __call__
+
+## SeamlessM4TFeatureExtractor
+
+[[autodoc]] SeamlessM4TFeatureExtractor
+ - __call__
+
+## SeamlessM4TProcessor
+
+[[autodoc]] SeamlessM4TProcessor
+ - __call__
+
+## SeamlessM4TCodeHifiGan
+
+[[autodoc]] SeamlessM4TCodeHifiGan
+
+
+## SeamlessM4THifiGan
+
+[[autodoc]] SeamlessM4THifiGan
+
+## SeamlessM4TTextToUnitModel
+
+[[autodoc]] SeamlessM4TTextToUnitModel
+
+## SeamlessM4TTextToUnitForConditionalGeneration
+
+[[autodoc]] SeamlessM4TTextToUnitForConditionalGeneration
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/seamless_m4t_v2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/seamless_m4t_v2.md
new file mode 100644
index 0000000000000000000000000000000000000000..aea34acc180b3835297c297c13f10e94f62f4a7f
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/seamless_m4t_v2.md
@@ -0,0 +1,194 @@
+
+
+# SeamlessM4T-v2
+
+## Overview
+
+The SeamlessM4T-v2 model was proposed in [Seamless: Multilingual Expressive and Streaming Speech Translation](https://ai.meta.com/research/publications/seamless-multilingual-expressive-and-streaming-speech-translation/) by the Seamless Communication team from Meta AI.
+
+SeamlessM4T-v2 is a collection of models designed to provide high quality translation, allowing people from different linguistic communities to communicate effortlessly through speech and text. It is an improvement on the [previous version](https://huggingface.co/docs/transformers/main/model_doc/seamless_m4t). For more details on the differences between v1 and v2, refer to section [Difference with SeamlessM4T-v1](#difference-with-seamlessm4t-v1).
+
+SeamlessM4T-v2 enables multiple tasks without relying on separate models:
+
+- Speech-to-speech translation (S2ST)
+- Speech-to-text translation (S2TT)
+- Text-to-speech translation (T2ST)
+- Text-to-text translation (T2TT)
+- Automatic speech recognition (ASR)
+
+[`SeamlessM4Tv2Model`] can perform all the above tasks, but each task also has its own dedicated sub-model.
+
+The abstract from the paper is the following:
+
+*Recent advancements in automatic speech translation have dramatically expanded language coverage, improved multimodal capabilities, and enabled a wide range of tasks and functionalities. That said, large-scale automatic speech translation systems today lack key features that help machine-mediated communication feel seamless when compared to human-to-human dialogue. In this work, we introduce a family of models that enable end-to-end expressive and multilingual translations in a streaming fashion. First, we contribute an improved version of the massively multilingual and multimodal SeamlessM4T model—SeamlessM4T v2. This newer model, incorporating an updated UnitY2 framework, was trained on more low-resource language data. The expanded version of SeamlessAlign adds 114,800 hours of automatically aligned data for a total of 76 languages. SeamlessM4T v2 provides the foundation on which our two newest models, SeamlessExpressive and SeamlessStreaming, are initiated. SeamlessExpressive enables translation that preserves vocal styles and prosody. Compared to previous efforts in expressive speech research, our work addresses certain underexplored aspects of prosody, such as speech rate and pauses, while also preserving the style of one’s voice. As for SeamlessStreaming, our model leverages the Efficient Monotonic Multihead Attention (EMMA) mechanism to generate low-latency target translations without waiting for complete source utterances. As the first of its kind, SeamlessStreaming enables simultaneous speech-to-speech/text translation for multiple source and target languages. To understand the performance of these models, we combined novel and modified versions of existing automatic metrics to evaluate prosody, latency, and robustness. For human evaluations, we adapted existing protocols tailored for measuring the most relevant attributes in the preservation of meaning, naturalness, and expressivity. To ensure that our models can be used safely and responsibly, we implemented the first known red-teaming effort for multimodal machine translation, a system for the detection and mitigation of added toxicity, a systematic evaluation of gender bias, and an inaudible localized watermarking mechanism designed to dampen the impact of deepfakes. Consequently, we bring major components from SeamlessExpressive and SeamlessStreaming together to form Seamless, the first publicly available system that unlocks expressive cross-lingual communication in real-time. In sum, Seamless gives us a pivotal look at the technical foundation needed to turn the Universal Speech Translator from a science fiction concept into a real-world technology. Finally, contributions in this work—including models, code, and a watermark detector—are publicly released and accessible at the link below.*
+
+## Usage
+
+In the following example, we'll load an Arabic audio sample and an English text sample and convert them into Russian speech and French text.
+
+First, load the processor and a checkpoint of the model:
+
+```python
+>>> from transformers import AutoProcessor, SeamlessM4Tv2Model
+
+>>> processor = AutoProcessor.from_pretrained("facebook/seamless-m4t-v2-large")
+>>> model = SeamlessM4Tv2Model.from_pretrained("facebook/seamless-m4t-v2-large")
+```
+
+You can seamlessly use this model on text or on audio, to generated either translated text or translated audio.
+
+Here is how to use the processor to process text and audio:
+
+```python
+>>> # let's load an audio sample from an Arabic speech corpus
+>>> from datasets import load_dataset
+>>> dataset = load_dataset("arabic_speech_corpus", split="test", streaming=True)
+>>> audio_sample = next(iter(dataset))["audio"]
+
+>>> # now, process it
+>>> audio_inputs = processor(audios=audio_sample["array"], return_tensors="pt")
+
+>>> # now, process some English text as well
+>>> text_inputs = processor(text = "Hello, my dog is cute", src_lang="eng", return_tensors="pt")
+```
+
+
+### Speech
+
+[`SeamlessM4Tv2Model`] can *seamlessly* generate text or speech with few or no changes. Let's target Russian voice translation:
+
+```python
+>>> audio_array_from_text = model.generate(**text_inputs, tgt_lang="rus")[0].cpu().numpy().squeeze()
+>>> audio_array_from_audio = model.generate(**audio_inputs, tgt_lang="rus")[0].cpu().numpy().squeeze()
+```
+
+With basically the same code, I've translated English text and Arabic speech to Russian speech samples.
+
+### Text
+
+Similarly, you can generate translated text from audio files or from text with the same model. You only have to pass `generate_speech=False` to [`SeamlessM4Tv2Model.generate`].
+This time, let's translate to French.
+
+```python
+>>> # from audio
+>>> output_tokens = model.generate(**audio_inputs, tgt_lang="fra", generate_speech=False)
+>>> translated_text_from_audio = processor.decode(output_tokens[0].tolist()[0], skip_special_tokens=True)
+
+>>> # from text
+>>> output_tokens = model.generate(**text_inputs, tgt_lang="fra", generate_speech=False)
+>>> translated_text_from_text = processor.decode(output_tokens[0].tolist()[0], skip_special_tokens=True)
+```
+
+### Tips
+
+
+#### 1. Use dedicated models
+
+[`SeamlessM4Tv2Model`] is transformers top level model to generate speech and text, but you can also use dedicated models that perform the task without additional components, thus reducing the memory footprint.
+For example, you can replace the audio-to-audio generation snippet with the model dedicated to the S2ST task, the rest is exactly the same code:
+
+```python
+>>> from transformers import SeamlessM4Tv2ForSpeechToSpeech
+>>> model = SeamlessM4Tv2ForSpeechToSpeech.from_pretrained("facebook/seamless-m4t-v2-large")
+```
+
+Or you can replace the text-to-text generation snippet with the model dedicated to the T2TT task, you only have to remove `generate_speech=False`.
+
+```python
+>>> from transformers import SeamlessM4Tv2ForTextToText
+>>> model = SeamlessM4Tv2ForTextToText.from_pretrained("facebook/seamless-m4t-v2-large")
+```
+
+Feel free to try out [`SeamlessM4Tv2ForSpeechToText`] and [`SeamlessM4Tv2ForTextToSpeech`] as well.
+
+#### 2. Change the speaker identity
+
+You have the possibility to change the speaker used for speech synthesis with the `speaker_id` argument. Some `speaker_id` works better than other for some languages!
+
+#### 3. Change the generation strategy
+
+You can use different [generation strategies](../generation_strategies) for text generation, e.g `.generate(input_ids=input_ids, text_num_beams=4, text_do_sample=True)` which will perform multinomial beam-search decoding on the text model. Note that speech generation only supports greedy - by default - or multinomial sampling, which can be used with e.g. `.generate(..., speech_do_sample=True, speech_temperature=0.6)`.
+
+#### 4. Generate speech and text at the same time
+
+Use `return_intermediate_token_ids=True` with [`SeamlessM4Tv2Model`] to return both speech and text !
+
+## Model architecture
+
+SeamlessM4T-v2 features a versatile architecture that smoothly handles the sequential generation of text and speech. This setup comprises two sequence-to-sequence (seq2seq) models. The first model translates the input modality into translated text, while the second model generates speech tokens, known as "unit tokens," from the translated text.
+
+Each modality has its own dedicated encoder with a unique architecture. Additionally, for speech output, a vocoder inspired by the [HiFi-GAN](https://arxiv.org/abs/2010.05646) architecture is placed on top of the second seq2seq model.
+
+### Difference with SeamlessM4T-v1
+
+The architecture of this new version differs from the first in a few aspects:
+
+#### Improvements on the second-pass model
+
+The second seq2seq model, named text-to-unit model, is now non-auto regressive, meaning that it computes units in a **single forward pass**. This achievement is made possible by:
+- the use of **character-level embeddings**, meaning that each character of the predicted translated text has its own embeddings, which are then used to predict the unit tokens.
+- the use of an intermediate duration predictor, that predicts speech duration at the **character-level** on the predicted translated text.
+- the use of a new text-to-unit decoder mixing convolutions and self-attention to handle longer context.
+
+#### Difference in the speech encoder
+
+The speech encoder, which is used during the first-pass generation process to predict the translated text, differs mainly from the previous speech encoder through these mechanisms:
+- the use of chunked attention mask to prevent attention across chunks, ensuring that each position attends only to positions within its own chunk and a fixed number of previous chunks.
+- the use of relative position embeddings which only considers distance between sequence elements rather than absolute positions. Please refer to [Self-Attentionwith Relative Position Representations (Shaw et al.)](https://arxiv.org/abs/1803.02155) for more details.
+- the use of a causal depth-wise convolution instead of a non-causal one.
+
+### Generation process
+
+Here's how the generation process works:
+
+- Input text or speech is processed through its specific encoder.
+- A decoder creates text tokens in the desired language.
+- If speech generation is required, the second seq2seq model, generates unit tokens in an non auto-regressive way.
+- These unit tokens are then passed through the final vocoder to produce the actual speech.
+
+
+This model was contributed by [ylacombe](https://huggingface.co/ylacombe). The original code can be found [here](https://github.com/facebookresearch/seamless_communication).
+
+## SeamlessM4Tv2Model
+
+[[autodoc]] SeamlessM4Tv2Model
+ - generate
+
+
+## SeamlessM4Tv2ForTextToSpeech
+
+[[autodoc]] SeamlessM4Tv2ForTextToSpeech
+ - generate
+
+
+## SeamlessM4Tv2ForSpeechToSpeech
+
+[[autodoc]] SeamlessM4Tv2ForSpeechToSpeech
+ - generate
+
+
+## SeamlessM4Tv2ForTextToText
+
+[[autodoc]] transformers.SeamlessM4Tv2ForTextToText
+ - forward
+ - generate
+
+## SeamlessM4Tv2ForSpeechToText
+
+[[autodoc]] transformers.SeamlessM4Tv2ForSpeechToText
+ - forward
+ - generate
+
+## SeamlessM4Tv2Config
+
+[[autodoc]] SeamlessM4Tv2Config
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/segformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/segformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..1dc38ef45b8eaaadca15ed749e2fab68c1c6133d
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/segformer.md
@@ -0,0 +1,173 @@
+
+
+# SegFormer
+
+## Overview
+
+The SegFormer model was proposed in [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://arxiv.org/abs/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping
+Luo. The model consists of a hierarchical Transformer encoder and a lightweight all-MLP decode head to achieve great
+results on image segmentation benchmarks such as ADE20K and Cityscapes.
+
+The abstract from the paper is the following:
+
+*We present SegFormer, a simple, efficient yet powerful semantic segmentation framework which unifies Transformers with
+lightweight multilayer perception (MLP) decoders. SegFormer has two appealing features: 1) SegFormer comprises a novel
+hierarchically structured Transformer encoder which outputs multiscale features. It does not need positional encoding,
+thereby avoiding the interpolation of positional codes which leads to decreased performance when the testing resolution
+differs from training. 2) SegFormer avoids complex decoders. The proposed MLP decoder aggregates information from
+different layers, and thus combining both local attention and global attention to render powerful representations. We
+show that this simple and lightweight design is the key to efficient segmentation on Transformers. We scale our
+approach up to obtain a series of models from SegFormer-B0 to SegFormer-B5, reaching significantly better performance
+and efficiency than previous counterparts. For example, SegFormer-B4 achieves 50.3% mIoU on ADE20K with 64M parameters,
+being 5x smaller and 2.2% better than the previous best method. Our best model, SegFormer-B5, achieves 84.0% mIoU on
+Cityscapes validation set and shows excellent zero-shot robustness on Cityscapes-C.*
+
+The figure below illustrates the architecture of SegFormer. Taken from the [original paper](https://arxiv.org/abs/2105.15203).
+
+
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The TensorFlow version
+of the model was contributed by [sayakpaul](https://huggingface.co/sayakpaul). The original code can be found [here](https://github.com/NVlabs/SegFormer).
+
+## Usage tips
+
+- SegFormer consists of a hierarchical Transformer encoder, and a lightweight all-MLP decoder head.
+ [`SegformerModel`] is the hierarchical Transformer encoder (which in the paper is also referred to
+ as Mix Transformer or MiT). [`SegformerForSemanticSegmentation`] adds the all-MLP decoder head on
+ top to perform semantic segmentation of images. In addition, there's
+ [`SegformerForImageClassification`] which can be used to - you guessed it - classify images. The
+ authors of SegFormer first pre-trained the Transformer encoder on ImageNet-1k to classify images. Next, they throw
+ away the classification head, and replace it by the all-MLP decode head. Next, they fine-tune the model altogether on
+ ADE20K, Cityscapes and COCO-stuff, which are important benchmarks for semantic segmentation. All checkpoints can be
+ found on the [hub](https://huggingface.co/models?other=segformer).
+- The quickest way to get started with SegFormer is by checking the [example notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/SegFormer) (which showcase both inference and
+ fine-tuning on custom data). One can also check out the [blog post](https://huggingface.co/blog/fine-tune-segformer) introducing SegFormer and illustrating how it can be fine-tuned on custom data.
+- TensorFlow users should refer to [this repository](https://github.com/deep-diver/segformer-tf-transformers) that shows off-the-shelf inference and fine-tuning.
+- One can also check out [this interactive demo on Hugging Face Spaces](https://huggingface.co/spaces/chansung/segformer-tf-transformers)
+ to try out a SegFormer model on custom images.
+- SegFormer works on any input size, as it pads the input to be divisible by `config.patch_sizes`.
+- One can use [`SegformerImageProcessor`] to prepare images and corresponding segmentation maps
+ for the model. Note that this image processor is fairly basic and does not include all data augmentations used in
+ the original paper. The original preprocessing pipelines (for the ADE20k dataset for instance) can be found [here](https://github.com/NVlabs/SegFormer/blob/master/local_configs/_base_/datasets/ade20k_repeat.py). The most
+ important preprocessing step is that images and segmentation maps are randomly cropped and padded to the same size,
+ such as 512x512 or 640x640, after which they are normalized.
+- One additional thing to keep in mind is that one can initialize [`SegformerImageProcessor`] with
+ `do_reduce_labels` set to `True` or `False`. In some datasets (like ADE20k), the 0 index is used in the annotated
+ segmentation maps for background. However, ADE20k doesn't include the "background" class in its 150 labels.
+ Therefore, `do_reduce_labels` is used to reduce all labels by 1, and to make sure no loss is computed for the
+ background class (i.e. it replaces 0 in the annotated maps by 255, which is the *ignore_index* of the loss function
+ used by [`SegformerForSemanticSegmentation`]). However, other datasets use the 0 index as
+ background class and include this class as part of all labels. In that case, `do_reduce_labels` should be set to
+ `False`, as loss should also be computed for the background class.
+- As most models, SegFormer comes in different sizes, the details of which can be found in the table below
+ (taken from Table 7 of the [original paper](https://arxiv.org/abs/2105.15203)).
+
+| **Model variant** | **Depths** | **Hidden sizes** | **Decoder hidden size** | **Params (M)** | **ImageNet-1k Top 1** |
+| :---------------: | ------------- | ------------------- | :---------------------: | :------------: | :-------------------: |
+| MiT-b0 | [2, 2, 2, 2] | [32, 64, 160, 256] | 256 | 3.7 | 70.5 |
+| MiT-b1 | [2, 2, 2, 2] | [64, 128, 320, 512] | 256 | 14.0 | 78.7 |
+| MiT-b2 | [3, 4, 6, 3] | [64, 128, 320, 512] | 768 | 25.4 | 81.6 |
+| MiT-b3 | [3, 4, 18, 3] | [64, 128, 320, 512] | 768 | 45.2 | 83.1 |
+| MiT-b4 | [3, 8, 27, 3] | [64, 128, 320, 512] | 768 | 62.6 | 83.6 |
+| MiT-b5 | [3, 6, 40, 3] | [64, 128, 320, 512] | 768 | 82.0 | 83.8 |
+
+Note that MiT in the above table refers to the Mix Transformer encoder backbone introduced in SegFormer. For
+SegFormer's results on the segmentation datasets like ADE20k, refer to the [paper](https://arxiv.org/abs/2105.15203).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with SegFormer.
+
+
+
+- [`SegformerForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- [Image classification task guide](../tasks/image_classification)
+
+Semantic segmentation:
+
+- [`SegformerForSemanticSegmentation`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/semantic-segmentation).
+- A blog on fine-tuning SegFormer on a custom dataset can be found [here](https://huggingface.co/blog/fine-tune-segformer).
+- More demo notebooks on SegFormer (both inference + fine-tuning on a custom dataset) can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/SegFormer).
+- [`TFSegformerForSemanticSegmentation`] is supported by this [example notebook](https://github.com/huggingface/notebooks/blob/main/examples/semantic_segmentation-tf.ipynb).
+- [Semantic segmentation task guide](../tasks/semantic_segmentation)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## SegformerConfig
+
+[[autodoc]] SegformerConfig
+
+## SegformerFeatureExtractor
+
+[[autodoc]] SegformerFeatureExtractor
+ - __call__
+ - post_process_semantic_segmentation
+
+## SegformerImageProcessor
+
+[[autodoc]] SegformerImageProcessor
+ - preprocess
+ - post_process_semantic_segmentation
+
+
+
+
+## SegformerModel
+
+[[autodoc]] SegformerModel
+ - forward
+
+## SegformerDecodeHead
+
+[[autodoc]] SegformerDecodeHead
+ - forward
+
+## SegformerForImageClassification
+
+[[autodoc]] SegformerForImageClassification
+ - forward
+
+## SegformerForSemanticSegmentation
+
+[[autodoc]] SegformerForSemanticSegmentation
+ - forward
+
+
+
+
+## TFSegformerDecodeHead
+
+[[autodoc]] TFSegformerDecodeHead
+ - call
+
+## TFSegformerModel
+
+[[autodoc]] TFSegformerModel
+ - call
+
+## TFSegformerForImageClassification
+
+[[autodoc]] TFSegformerForImageClassification
+ - call
+
+## TFSegformerForSemanticSegmentation
+
+[[autodoc]] TFSegformerForSemanticSegmentation
+ - call
+
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/seggpt.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/seggpt.md
new file mode 100644
index 0000000000000000000000000000000000000000..b53f5d6ca1500bcc599f01ccc4c68e891c6b4cca
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/seggpt.md
@@ -0,0 +1,91 @@
+
+
+# SegGPT
+
+## Overview
+
+The SegGPT model was proposed in [SegGPT: Segmenting Everything In Context](https://arxiv.org/abs/2304.03284) by Xinlong Wang, Xiaosong Zhang, Yue Cao, Wen Wang, Chunhua Shen, Tiejun Huang. SegGPT employs a decoder-only Transformer that can generate a segmentation mask given an input image, a prompt image and its corresponding prompt mask. The model achieves remarkable one-shot results with 56.1 mIoU on COCO-20 and 85.6 mIoU on FSS-1000.
+
+The abstract from the paper is the following:
+
+*We present SegGPT, a generalist model for segmenting everything in context. We unify various segmentation tasks into a generalist in-context learning framework that accommodates different kinds of segmentation data by transforming them into the same format of images. The training of SegGPT is formulated as an in-context coloring problem with random color mapping for each data sample. The objective is to accomplish diverse tasks according to the context, rather than relying on specific colors. After training, SegGPT can perform arbitrary segmentation tasks in images or videos via in-context inference, such as object instance, stuff, part, contour, and text. SegGPT is evaluated on a broad range of tasks, including few-shot semantic segmentation, video object segmentation, semantic segmentation, and panoptic segmentation. Our results show strong capabilities in segmenting in-domain and out-of*
+
+Tips:
+- One can use [`SegGptImageProcessor`] to prepare image input, prompt and mask to the model.
+- One can either use segmentation maps or RGB images as prompt masks. If using the latter make sure to set `do_convert_rgb=False` in the `preprocess` method.
+- It's highly advisable to pass `num_labels` when using `segmentation_maps` (not considering background) during preprocessing and postprocessing with [`SegGptImageProcessor`] for your use case.
+- When doing inference with [`SegGptForImageSegmentation`] if your `batch_size` is greater than 1 you can use feature ensemble across your images by passing `feature_ensemble=True` in the forward method.
+
+Here's how to use the model for one-shot semantic segmentation:
+
+```python
+import torch
+from datasets import load_dataset
+from transformers import SegGptImageProcessor, SegGptForImageSegmentation
+
+checkpoint = "BAAI/seggpt-vit-large"
+image_processor = SegGptImageProcessor.from_pretrained(checkpoint)
+model = SegGptForImageSegmentation.from_pretrained(checkpoint)
+
+dataset_id = "EduardoPacheco/FoodSeg103"
+ds = load_dataset(dataset_id, split="train")
+# Number of labels in FoodSeg103 (not including background)
+num_labels = 103
+
+image_input = ds[4]["image"]
+ground_truth = ds[4]["label"]
+image_prompt = ds[29]["image"]
+mask_prompt = ds[29]["label"]
+
+inputs = image_processor(
+ images=image_input,
+ prompt_images=image_prompt,
+ segmentation_maps=mask_prompt,
+ num_labels=num_labels,
+ return_tensors="pt"
+)
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+target_sizes = [image_input.size[::-1]]
+mask = image_processor.post_process_semantic_segmentation(outputs, target_sizes, num_labels=num_labels)[0]
+```
+
+This model was contributed by [EduardoPacheco](https://huggingface.co/EduardoPacheco).
+The original code can be found [here]([(https://github.com/baaivision/Painter/tree/main)).
+
+
+## SegGptConfig
+
+[[autodoc]] SegGptConfig
+
+## SegGptImageProcessor
+
+[[autodoc]] SegGptImageProcessor
+ - preprocess
+ - post_process_semantic_segmentation
+
+## SegGptModel
+
+[[autodoc]] SegGptModel
+ - forward
+
+## SegGptForImageSegmentation
+
+[[autodoc]] SegGptForImageSegmentation
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/sew-d.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/sew-d.md
new file mode 100644
index 0000000000000000000000000000000000000000..013e404bd045b8f2ba87f2e41151e7f952d47537
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/sew-d.md
@@ -0,0 +1,65 @@
+
+
+# SEW-D
+
+## Overview
+
+SEW-D (Squeezed and Efficient Wav2Vec with Disentangled attention) was proposed in [Performance-Efficiency Trade-offs
+in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim,
+Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+
+The abstract from the paper is the following:
+
+*This paper is a study of performance-efficiency trade-offs in pre-trained models for automatic speech recognition
+(ASR). We focus on wav2vec 2.0, and formalize several architecture designs that influence both the model performance
+and its efficiency. Putting together all our observations, we introduce SEW (Squeezed and Efficient Wav2vec), a
+pre-trained model architecture with significant improvements along both performance and efficiency dimensions across a
+variety of training setups. For example, under the 100h-960h semi-supervised setup on LibriSpeech, SEW achieves a 1.9x
+inference speedup compared to wav2vec 2.0, with a 13.5% relative reduction in word error rate. With a similar inference
+time, SEW reduces word error rate by 25-50% across different model sizes.*
+
+This model was contributed by [anton-l](https://huggingface.co/anton-l).
+
+## Usage tips
+
+- SEW-D is a speech model that accepts a float array corresponding to the raw waveform of the speech signal.
+- SEWDForCTC is fine-tuned using connectionist temporal classification (CTC) so the model output has to be decoded
+ using [`Wav2Vec2CTCTokenizer`].
+
+## Resources
+
+- [Audio classification task guide](../tasks/audio_classification)
+- [Automatic speech recognition task guide](../tasks/asr)
+
+## SEWDConfig
+
+[[autodoc]] SEWDConfig
+
+## SEWDModel
+
+[[autodoc]] SEWDModel
+ - forward
+
+## SEWDForCTC
+
+[[autodoc]] SEWDForCTC
+ - forward
+
+## SEWDForSequenceClassification
+
+[[autodoc]] SEWDForSequenceClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/sew.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/sew.md
new file mode 100644
index 0000000000000000000000000000000000000000..ee8a36a4dcb2faa8e38c3b9b9ea3f944c3c0859b
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/sew.md
@@ -0,0 +1,65 @@
+
+
+# SEW
+
+## Overview
+
+SEW (Squeezed and Efficient Wav2Vec) was proposed in [Performance-Efficiency Trade-offs in Unsupervised Pre-training
+for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q.
+Weinberger, Yoav Artzi.
+
+The abstract from the paper is the following:
+
+*This paper is a study of performance-efficiency trade-offs in pre-trained models for automatic speech recognition
+(ASR). We focus on wav2vec 2.0, and formalize several architecture designs that influence both the model performance
+and its efficiency. Putting together all our observations, we introduce SEW (Squeezed and Efficient Wav2vec), a
+pre-trained model architecture with significant improvements along both performance and efficiency dimensions across a
+variety of training setups. For example, under the 100h-960h semi-supervised setup on LibriSpeech, SEW achieves a 1.9x
+inference speedup compared to wav2vec 2.0, with a 13.5% relative reduction in word error rate. With a similar inference
+time, SEW reduces word error rate by 25-50% across different model sizes.*
+
+This model was contributed by [anton-l](https://huggingface.co/anton-l).
+
+## Usage tips
+
+- SEW is a speech model that accepts a float array corresponding to the raw waveform of the speech signal.
+- SEWForCTC is fine-tuned using connectionist temporal classification (CTC) so the model output has to be decoded using
+ [`Wav2Vec2CTCTokenizer`].
+
+## Resources
+
+- [Audio classification task guide](../tasks/audio_classification)
+- [Automatic speech recognition task guide](../tasks/asr)
+
+## SEWConfig
+
+[[autodoc]] SEWConfig
+
+## SEWModel
+
+[[autodoc]] SEWModel
+ - forward
+
+## SEWForCTC
+
+[[autodoc]] SEWForCTC
+ - forward
+
+## SEWForSequenceClassification
+
+[[autodoc]] SEWForSequenceClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/siglip.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/siglip.md
new file mode 100644
index 0000000000000000000000000000000000000000..88e38cbb590edcbbf245d4fcd7ec6c49151a2744
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/siglip.md
@@ -0,0 +1,243 @@
+
+
+# SigLIP
+
+## Overview
+
+The SigLIP model was proposed in [Sigmoid Loss for Language Image Pre-Training](https://arxiv.org/abs/2303.15343) by Xiaohua Zhai, Basil Mustafa, Alexander Kolesnikov, Lucas Beyer. SigLIP proposes to replace the loss function used in [CLIP](clip) by a simple pairwise sigmoid loss. This results in better performance in terms of zero-shot classification accuracy on ImageNet.
+
+The abstract from the paper is the following:
+
+*We propose a simple pairwise Sigmoid loss for Language-Image Pre-training (SigLIP). Unlike standard contrastive learning with softmax normalization, the sigmoid loss operates solely on image-text pairs and does not require a global view of the pairwise similarities for normalization. The sigmoid loss simultaneously allows further scaling up the batch size, while also performing better at smaller batch sizes. Combined with Locked-image Tuning, with only four TPUv4 chips, we train a SigLiT model that achieves 84.5% ImageNet zero-shot accuracy in two days. The disentanglement of the batch size from the loss further allows us to study the impact of examples vs pairs and negative to positive ratio. Finally, we push the batch size to the extreme, up to one million, and find that the benefits of growing batch size quickly diminish, with a more reasonable batch size of 32k being sufficient.*
+
+## Usage tips
+
+- Usage of SigLIP is similar to [CLIP](clip). The main difference is the training loss, which does not require a global view of all the pairwise similarities of images and texts within a batch. One needs to apply the sigmoid activation function to the logits, rather than the softmax.
+- Training is supported but does not use `torch.distributed` utilities which may limit the scalability of batch size. However, DDP and FDSP works on single-node multi-gpu setup.
+- When using the standalone [`SiglipTokenizer`] or [`SiglipProcessor`], make sure to pass `padding="max_length"` as that's how the model was trained.
+- To get the same results as the pipeline, a prompt template of "This is a photo of {label}." should be used.
+
+
+
+ SigLIP evaluation results compared to CLIP. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/google-research/big_vision/tree/main).
+
+## Usage example
+
+There are 2 main ways to use SigLIP: either using the pipeline API, which abstracts away all the complexity for you, or by using the `SiglipModel` class yourself.
+
+### Pipeline API
+
+The pipeline allows to use the model in a few lines of code:
+
+```python
+>>> from transformers import pipeline
+>>> from PIL import Image
+>>> import requests
+
+>>> # load pipe
+>>> image_classifier = pipeline(task="zero-shot-image-classification", model="google/siglip-base-patch16-224")
+
+>>> # load image
+>>> url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> # inference
+>>> candidate_labels = ["2 cats", "a plane", "a remote"]
+>>> outputs = image_classifier(image, candidate_labels=candidate_labels)
+>>> outputs = [{"score": round(output["score"], 4), "label": output["label"] } for output in outputs]
+>>> print(outputs)
+[{'score': 0.1979, 'label': '2 cats'}, {'score': 0.0, 'label': 'a remote'}, {'score': 0.0, 'label': 'a plane'}]
+```
+
+### Using the model yourself
+
+If you want to do the pre- and postprocessing yourself, here's how to do that:
+
+```python
+>>> from PIL import Image
+>>> import requests
+>>> from transformers import AutoProcessor, AutoModel
+>>> import torch
+
+>>> model = AutoModel.from_pretrained("google/siglip-base-patch16-224")
+>>> processor = AutoProcessor.from_pretrained("google/siglip-base-patch16-224")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> candidate_labels = ["2 cats", "2 dogs"]
+# follows the pipeline prompt template to get same results
+>>> texts = [f'This is a photo of {label}.' for label in candidate_labels]
+>>> # important: we pass `padding=max_length` since the model was trained with this
+>>> inputs = processor(text=texts, images=image, padding="max_length", return_tensors="pt")
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> logits_per_image = outputs.logits_per_image
+>>> probs = torch.sigmoid(logits_per_image) # these are the probabilities
+>>> print(f"{probs[0][0]:.1%} that image 0 is '{candidate_labels[0]}'")
+31.9% that image 0 is 'a photo of 2 cats'
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with SigLIP.
+
+- [Zero-shot image classification task guide](../tasks/zero_shot_image_classification_md)
+- Demo notebooks for SigLIP can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/SigLIP). 🌎
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+## Combining SigLIP and Flash Attention 2
+
+First, make sure to install the latest version of Flash Attention 2.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Make also sure that you have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of flash-attn repository. Make also sure to load your model in half-precision (e.g. `torch.float16``)
+
+To load and run a model using Flash Attention 2, refer to the snippet below:
+
+```python
+>>> import torch
+>>> import requests
+>>> from PIL import Image
+>>> from transformers import SiglipProcessor, SiglipModel
+>>> device = "cuda" # the device to load the model onto
+
+>>> model = SiglipModel.from_pretrained(
+... "google/siglip-so400m-patch14-384",
+... attn_implementation="flash_attention_2",
+... torch_dtype=torch.float16,
+... device_map=device,
+... )
+>>> processor = SiglipProcessor.from_pretrained("google/siglip-so400m-patch14-384")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> candidate_labels = ["2 cats", "2 dogs"]
+# follows the pipeline prompt template to get same results
+>>> texts = [f'This is a photo of {label}.' for label in candidate_labels]
+# important: we pass `padding=max_length` since the model was trained with this
+>>> inputs = processor(text=texts, images=image, padding="max_length", return_tensors="pt")
+>>> inputs.to(device)
+
+>>> with torch.no_grad():
+... with torch.autocast(device):
+... outputs = model(**inputs)
+
+>>> logits_per_image = outputs.logits_per_image
+>>> probs = torch.sigmoid(logits_per_image) # these are the probabilities
+>>> print(f"{probs[0][0]:.1%} that image 0 is '{candidate_labels[0]}'")
+51.3% that image 0 is 'This is a photo of 2 cats.'
+```
+
+
+## Using Scaled Dot Product Attention (SDPA)
+
+PyTorch includes a native scaled dot-product attention (SDPA) operator as part of `torch.nn.functional`. This function
+encompasses several implementations that can be applied depending on the inputs and the hardware in use. See the
+[official documentation](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)
+or the [GPU Inference](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)
+page for more information.
+
+You may set `attn_implementation="sdpa"` in `from_pretrained()` to explicitly request SDPA to be used. Make sure you have `torch>=2.1.1`.
+
+```python
+>>> from transformers import SiglipModel
+
+>>> model = SiglipModel.from_pretrained(
+... "google/siglip-so400m-patch14-384",
+... attn_implementation="sdpa",
+... torch_dtype=torch.float16,
+... device_map=device,
+... )
+```
+
+For the best speedups, we recommend loading the model in half-precision (e.g. `torch.float16` or `torch.bfloat16`).
+
+
+## Expected speedups
+
+Below is an expected speedup diagram that compares inference time between the native implementation in transformers using `google/siglip-so400m-patch14-384` checkpoint in `float16` precision and the Flash Attention 2 / SDPA version of the model using different batch sizes.
+
+
+
+
+
+
+## SiglipConfig
+
+[[autodoc]] SiglipConfig
+ - from_text_vision_configs
+
+## SiglipTextConfig
+
+[[autodoc]] SiglipTextConfig
+
+## SiglipVisionConfig
+
+[[autodoc]] SiglipVisionConfig
+
+## SiglipTokenizer
+
+[[autodoc]] SiglipTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## SiglipImageProcessor
+
+[[autodoc]] SiglipImageProcessor
+ - preprocess
+
+## SiglipProcessor
+
+[[autodoc]] SiglipProcessor
+
+## SiglipModel
+
+[[autodoc]] SiglipModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## SiglipTextModel
+
+[[autodoc]] SiglipTextModel
+ - forward
+
+## SiglipVisionModel
+
+[[autodoc]] SiglipVisionModel
+ - forward
+
+
+## SiglipForImageClassification
+
+[[autodoc]] SiglipForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/speech-encoder-decoder.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/speech-encoder-decoder.md
new file mode 100644
index 0000000000000000000000000000000000000000..7e2bcef98abce8d96043f1a887345cf4e3238f67
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/speech-encoder-decoder.md
@@ -0,0 +1,132 @@
+
+
+# Speech Encoder Decoder Models
+
+The [`SpeechEncoderDecoderModel`] can be used to initialize a speech-to-text model
+with any pretrained speech autoencoding model as the encoder (*e.g.* [Wav2Vec2](wav2vec2), [Hubert](hubert)) and any pretrained autoregressive model as the decoder.
+
+The effectiveness of initializing speech-sequence-to-text-sequence models with pretrained checkpoints for speech
+recognition and speech translation has *e.g.* been shown in [Large-Scale Self- and Semi-Supervised Learning for Speech
+Translation](https://arxiv.org/abs/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli,
+Alexis Conneau.
+
+An example of how to use a [`SpeechEncoderDecoderModel`] for inference can be seen in [Speech2Text2](speech_to_text_2).
+
+## Randomly initializing `SpeechEncoderDecoderModel` from model configurations.
+
+[`SpeechEncoderDecoderModel`] can be randomly initialized from an encoder and a decoder config. In the following example, we show how to do this using the default [`Wav2Vec2Model`] configuration for the encoder
+and the default [`BertForCausalLM`] configuration for the decoder.
+
+```python
+>>> from transformers import BertConfig, Wav2Vec2Config, SpeechEncoderDecoderConfig, SpeechEncoderDecoderModel
+
+>>> config_encoder = Wav2Vec2Config()
+>>> config_decoder = BertConfig()
+
+>>> config = SpeechEncoderDecoderConfig.from_encoder_decoder_configs(config_encoder, config_decoder)
+>>> model = SpeechEncoderDecoderModel(config=config)
+```
+
+## Initialising `SpeechEncoderDecoderModel` from a pretrained encoder and a pretrained decoder.
+
+[`SpeechEncoderDecoderModel`] can be initialized from a pretrained encoder checkpoint and a pretrained decoder checkpoint. Note that any pretrained Transformer-based speech model, *e.g.* [Wav2Vec2](wav2vec2), [Hubert](hubert) can serve as the encoder and both pretrained auto-encoding models, *e.g.* BERT, pretrained causal language models, *e.g.* GPT2, as well as the pretrained decoder part of sequence-to-sequence models, *e.g.* decoder of BART, can be used as the decoder.
+Depending on which architecture you choose as the decoder, the cross-attention layers might be randomly initialized.
+Initializing [`SpeechEncoderDecoderModel`] from a pretrained encoder and decoder checkpoint requires the model to be fine-tuned on a downstream task, as has been shown in [the *Warm-starting-encoder-decoder blog post*](https://huggingface.co/blog/warm-starting-encoder-decoder).
+To do so, the `SpeechEncoderDecoderModel` class provides a [`SpeechEncoderDecoderModel.from_encoder_decoder_pretrained`] method.
+
+```python
+>>> from transformers import SpeechEncoderDecoderModel
+
+>>> model = SpeechEncoderDecoderModel.from_encoder_decoder_pretrained(
+... "facebook/hubert-large-ll60k", "google-bert/bert-base-uncased"
+... )
+```
+
+## Loading an existing `SpeechEncoderDecoderModel` checkpoint and perform inference.
+
+To load fine-tuned checkpoints of the `SpeechEncoderDecoderModel` class, [`SpeechEncoderDecoderModel`] provides the `from_pretrained(...)` method just like any other model architecture in Transformers.
+
+To perform inference, one uses the [`generate`] method, which allows to autoregressively generate text. This method supports various forms of decoding, such as greedy, beam search and multinomial sampling.
+
+```python
+>>> from transformers import Wav2Vec2Processor, SpeechEncoderDecoderModel
+>>> from datasets import load_dataset
+>>> import torch
+
+>>> # load a fine-tuned speech translation model and corresponding processor
+>>> model = SpeechEncoderDecoderModel.from_pretrained("facebook/wav2vec2-xls-r-300m-en-to-15")
+>>> processor = Wav2Vec2Processor.from_pretrained("facebook/wav2vec2-xls-r-300m-en-to-15")
+
+>>> # let's perform inference on a piece of English speech (which we'll translate to German)
+>>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+>>> input_values = processor(ds[0]["audio"]["array"], return_tensors="pt").input_values
+
+>>> # autoregressively generate transcription (uses greedy decoding by default)
+>>> generated_ids = model.generate(input_values)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+>>> print(generated_text)
+Mr. Quilter ist der Apostel der Mittelschicht und wir freuen uns, sein Evangelium willkommen heißen zu können.
+```
+
+## Training
+
+Once the model is created, it can be fine-tuned similar to BART, T5 or any other encoder-decoder model on a dataset of (speech, text) pairs.
+As you can see, only 2 inputs are required for the model in order to compute a loss: `input_values` (which are the
+speech inputs) and `labels` (which are the `input_ids` of the encoded target sequence).
+
+```python
+>>> from transformers import AutoTokenizer, AutoFeatureExtractor, SpeechEncoderDecoderModel
+>>> from datasets import load_dataset
+
+>>> encoder_id = "facebook/wav2vec2-base-960h" # acoustic model encoder
+>>> decoder_id = "google-bert/bert-base-uncased" # text decoder
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained(encoder_id)
+>>> tokenizer = AutoTokenizer.from_pretrained(decoder_id)
+>>> # Combine pre-trained encoder and pre-trained decoder to form a Seq2Seq model
+>>> model = SpeechEncoderDecoderModel.from_encoder_decoder_pretrained(encoder_id, decoder_id)
+
+>>> model.config.decoder_start_token_id = tokenizer.cls_token_id
+>>> model.config.pad_token_id = tokenizer.pad_token_id
+
+>>> # load an audio input and pre-process (normalise mean/std to 0/1)
+>>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+>>> input_values = feature_extractor(ds[0]["audio"]["array"], return_tensors="pt").input_values
+
+>>> # load its corresponding transcription and tokenize to generate labels
+>>> labels = tokenizer(ds[0]["text"], return_tensors="pt").input_ids
+
+>>> # the forward function automatically creates the correct decoder_input_ids
+>>> loss = model(input_values=input_values, labels=labels).loss
+>>> loss.backward()
+```
+
+## SpeechEncoderDecoderConfig
+
+[[autodoc]] SpeechEncoderDecoderConfig
+
+## SpeechEncoderDecoderModel
+
+[[autodoc]] SpeechEncoderDecoderModel
+ - forward
+ - from_encoder_decoder_pretrained
+
+## FlaxSpeechEncoderDecoderModel
+
+[[autodoc]] FlaxSpeechEncoderDecoderModel
+ - __call__
+ - from_encoder_decoder_pretrained
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/speech_to_text.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/speech_to_text.md
new file mode 100644
index 0000000000000000000000000000000000000000..23512b323af6b43288337feeb07f0d7821e3f956
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/speech_to_text.md
@@ -0,0 +1,152 @@
+
+
+# Speech2Text
+
+## Overview
+
+The Speech2Text model was proposed in [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino. It's a
+transformer-based seq2seq (encoder-decoder) model designed for end-to-end Automatic Speech Recognition (ASR) and Speech
+Translation (ST). It uses a convolutional downsampler to reduce the length of speech inputs by 3/4th before they are
+fed into the encoder. The model is trained with standard autoregressive cross-entropy loss and generates the
+transcripts/translations autoregressively. Speech2Text has been fine-tuned on several datasets for ASR and ST:
+[LibriSpeech](http://www.openslr.org/12), [CoVoST 2](https://github.com/facebookresearch/covost), [MuST-C](https://ict.fbk.eu/must-c/).
+
+This model was contributed by [valhalla](https://huggingface.co/valhalla). The original code can be found [here](https://github.com/pytorch/fairseq/tree/master/examples/speech_to_text).
+
+## Inference
+
+Speech2Text is a speech model that accepts a float tensor of log-mel filter-bank features extracted from the speech
+signal. It's a transformer-based seq2seq model, so the transcripts/translations are generated autoregressively. The
+`generate()` method can be used for inference.
+
+The [`Speech2TextFeatureExtractor`] class is responsible for extracting the log-mel filter-bank
+features. The [`Speech2TextProcessor`] wraps [`Speech2TextFeatureExtractor`] and
+[`Speech2TextTokenizer`] into a single instance to both extract the input features and decode the
+predicted token ids.
+
+The feature extractor depends on `torchaudio` and the tokenizer depends on `sentencepiece` so be sure to
+install those packages before running the examples. You could either install those as extra speech dependencies with
+`pip install transformers"[speech, sentencepiece]"` or install the packages separately with `pip install torchaudio sentencepiece`. Also `torchaudio` requires the development version of the [libsndfile](http://www.mega-nerd.com/libsndfile/) package which can be installed via a system package manager. On Ubuntu it can
+be installed as follows: `apt install libsndfile1-dev`
+
+- ASR and Speech Translation
+
+```python
+>>> import torch
+>>> from transformers import Speech2TextProcessor, Speech2TextForConditionalGeneration
+>>> from datasets import load_dataset
+
+>>> model = Speech2TextForConditionalGeneration.from_pretrained("facebook/s2t-small-librispeech-asr")
+>>> processor = Speech2TextProcessor.from_pretrained("facebook/s2t-small-librispeech-asr")
+
+
+>>> ds = load_dataset("hf-internal-testing/librispeech_asr_demo", "clean", split="validation")
+
+>>> inputs = processor(ds[0]["audio"]["array"], sampling_rate=ds[0]["audio"]["sampling_rate"], return_tensors="pt")
+>>> generated_ids = model.generate(inputs["input_features"], attention_mask=inputs["attention_mask"])
+
+>>> transcription = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> transcription
+['mister quilter is the apostle of the middle classes and we are glad to welcome his gospel']
+```
+
+- Multilingual speech translation
+
+ For multilingual speech translation models, `eos_token_id` is used as the `decoder_start_token_id` and
+ the target language id is forced as the first generated token. To force the target language id as the first
+ generated token, pass the `forced_bos_token_id` parameter to the `generate()` method. The following
+ example shows how to transate English speech to French text using the *facebook/s2t-medium-mustc-multilingual-st*
+ checkpoint.
+
+```python
+>>> import torch
+>>> from transformers import Speech2TextProcessor, Speech2TextForConditionalGeneration
+>>> from datasets import load_dataset
+
+>>> model = Speech2TextForConditionalGeneration.from_pretrained("facebook/s2t-medium-mustc-multilingual-st")
+>>> processor = Speech2TextProcessor.from_pretrained("facebook/s2t-medium-mustc-multilingual-st")
+
+>>> ds = load_dataset("hf-internal-testing/librispeech_asr_demo", "clean", split="validation")
+
+>>> inputs = processor(ds[0]["audio"]["array"], sampling_rate=ds[0]["audio"]["sampling_rate"], return_tensors="pt")
+>>> generated_ids = model.generate(
+... inputs["input_features"],
+... attention_mask=inputs["attention_mask"],
+... forced_bos_token_id=processor.tokenizer.lang_code_to_id["fr"],
+... )
+
+>>> translation = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> translation
+["(Vidéo) Si M. Kilder est l'apossible des classes moyennes, et nous sommes heureux d'être accueillis dans son évangile."]
+```
+
+See the [model hub](https://huggingface.co/models?filter=speech_to_text) to look for Speech2Text checkpoints.
+
+## Speech2TextConfig
+
+[[autodoc]] Speech2TextConfig
+
+## Speech2TextTokenizer
+
+[[autodoc]] Speech2TextTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## Speech2TextFeatureExtractor
+
+[[autodoc]] Speech2TextFeatureExtractor
+ - __call__
+
+## Speech2TextProcessor
+
+[[autodoc]] Speech2TextProcessor
+ - __call__
+ - from_pretrained
+ - save_pretrained
+ - batch_decode
+ - decode
+
+
+
+
+## Speech2TextModel
+
+[[autodoc]] Speech2TextModel
+ - forward
+
+## Speech2TextForConditionalGeneration
+
+[[autodoc]] Speech2TextForConditionalGeneration
+ - forward
+
+
+
+
+## TFSpeech2TextModel
+
+[[autodoc]] TFSpeech2TextModel
+ - call
+
+## TFSpeech2TextForConditionalGeneration
+
+[[autodoc]] TFSpeech2TextForConditionalGeneration
+ - call
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/speech_to_text_2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/speech_to_text_2.md
new file mode 100644
index 0000000000000000000000000000000000000000..fc2d0357c546c7fe81ea9394ebf585e3a7753204
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/speech_to_text_2.md
@@ -0,0 +1,135 @@
+
+
+# Speech2Text2
+
+
+
+ This model is in maintenance mode only, we don't accept any new PRs changing its code.
+ If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+ You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The Speech2Text2 model is used together with [Wav2Vec2](wav2vec2) for Speech Translation models proposed in
+[Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://arxiv.org/abs/2104.06678) by
+Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
+
+Speech2Text2 is a *decoder-only* transformer model that can be used with any speech *encoder-only*, such as
+[Wav2Vec2](wav2vec2) or [HuBERT](hubert) for Speech-to-Text tasks. Please refer to the
+[SpeechEncoderDecoder](speech-encoder-decoder) class on how to combine Speech2Text2 with any speech *encoder-only*
+model.
+
+This model was contributed by [Patrick von Platen](https://huggingface.co/patrickvonplaten).
+
+The original code can be found [here](https://github.com/pytorch/fairseq/blob/1f7ef9ed1e1061f8c7f88f8b94c7186834398690/fairseq/models/wav2vec/wav2vec2_asr.py#L266).
+
+## Usage tips
+
+- Speech2Text2 achieves state-of-the-art results on the CoVoST Speech Translation dataset. For more information, see
+ the [official models](https://huggingface.co/models?other=speech2text2) .
+- Speech2Text2 is always used within the [SpeechEncoderDecoder](speech-encoder-decoder) framework.
+- Speech2Text2's tokenizer is based on [fastBPE](https://github.com/glample/fastBPE).
+
+## Inference
+
+Speech2Text2's [`SpeechEncoderDecoderModel`] model accepts raw waveform input values from speech and
+makes use of [`~generation.GenerationMixin.generate`] to translate the input speech
+autoregressively to the target language.
+
+The [`Wav2Vec2FeatureExtractor`] class is responsible for preprocessing the input speech and
+[`Speech2Text2Tokenizer`] decodes the generated target tokens to the target string. The
+[`Speech2Text2Processor`] wraps [`Wav2Vec2FeatureExtractor`] and
+[`Speech2Text2Tokenizer`] into a single instance to both extract the input features and decode the
+predicted token ids.
+
+- Step-by-step Speech Translation
+
+```python
+>>> import torch
+>>> from transformers import Speech2Text2Processor, SpeechEncoderDecoderModel
+>>> from datasets import load_dataset
+>>> import soundfile as sf
+
+>>> model = SpeechEncoderDecoderModel.from_pretrained("facebook/s2t-wav2vec2-large-en-de")
+>>> processor = Speech2Text2Processor.from_pretrained("facebook/s2t-wav2vec2-large-en-de")
+
+
+>>> def map_to_array(batch):
+... speech, _ = sf.read(batch["file"])
+... batch["speech"] = speech
+... return batch
+
+
+>>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+>>> ds = ds.map(map_to_array)
+
+>>> inputs = processor(ds["speech"][0], sampling_rate=16_000, return_tensors="pt")
+>>> generated_ids = model.generate(inputs=inputs["input_values"], attention_mask=inputs["attention_mask"])
+
+>>> transcription = processor.batch_decode(generated_ids)
+```
+
+- Speech Translation via Pipelines
+
+ The automatic speech recognition pipeline can also be used to translate speech in just a couple lines of code
+
+```python
+>>> from datasets import load_dataset
+>>> from transformers import pipeline
+
+>>> librispeech_en = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+>>> asr = pipeline(
+... "automatic-speech-recognition",
+... model="facebook/s2t-wav2vec2-large-en-de",
+... feature_extractor="facebook/s2t-wav2vec2-large-en-de",
+... )
+
+>>> translation_de = asr(librispeech_en[0]["file"])
+```
+
+See [model hub](https://huggingface.co/models?filter=speech2text2) to look for Speech2Text2 checkpoints.
+
+## Resources
+
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## Speech2Text2Config
+
+[[autodoc]] Speech2Text2Config
+
+## Speech2TextTokenizer
+
+[[autodoc]] Speech2Text2Tokenizer
+ - batch_decode
+ - decode
+ - save_vocabulary
+
+## Speech2Text2Processor
+
+[[autodoc]] Speech2Text2Processor
+ - __call__
+ - from_pretrained
+ - save_pretrained
+ - batch_decode
+ - decode
+
+## Speech2Text2ForCausalLM
+
+[[autodoc]] Speech2Text2ForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/speecht5.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/speecht5.md
new file mode 100644
index 0000000000000000000000000000000000000000..4d5e2098a542190fc77bca57676722545f412843
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/speecht5.md
@@ -0,0 +1,85 @@
+
+
+# SpeechT5
+
+## Overview
+
+The SpeechT5 model was proposed in [SpeechT5: Unified-Modal Encoder-Decoder Pre-Training for Spoken Language Processing](https://arxiv.org/abs/2110.07205) by Junyi Ao, Rui Wang, Long Zhou, Chengyi Wang, Shuo Ren, Yu Wu, Shujie Liu, Tom Ko, Qing Li, Yu Zhang, Zhihua Wei, Yao Qian, Jinyu Li, Furu Wei.
+
+The abstract from the paper is the following:
+
+*Motivated by the success of T5 (Text-To-Text Transfer Transformer) in pre-trained natural language processing models, we propose a unified-modal SpeechT5 framework that explores the encoder-decoder pre-training for self-supervised speech/text representation learning. The SpeechT5 framework consists of a shared encoder-decoder network and six modal-specific (speech/text) pre/post-nets. After preprocessing the input speech/text through the pre-nets, the shared encoder-decoder network models the sequence-to-sequence transformation, and then the post-nets generate the output in the speech/text modality based on the output of the decoder. Leveraging large-scale unlabeled speech and text data, we pre-train SpeechT5 to learn a unified-modal representation, hoping to improve the modeling capability for both speech and text. To align the textual and speech information into this unified semantic space, we propose a cross-modal vector quantization approach that randomly mixes up speech/text states with latent units as the interface between encoder and decoder. Extensive evaluations show the superiority of the proposed SpeechT5 framework on a wide variety of spoken language processing tasks, including automatic speech recognition, speech synthesis, speech translation, voice conversion, speech enhancement, and speaker identification.*
+
+This model was contributed by [Matthijs](https://huggingface.co/Matthijs). The original code can be found [here](https://github.com/microsoft/SpeechT5).
+
+## SpeechT5Config
+
+[[autodoc]] SpeechT5Config
+
+## SpeechT5HifiGanConfig
+
+[[autodoc]] SpeechT5HifiGanConfig
+
+## SpeechT5Tokenizer
+
+[[autodoc]] SpeechT5Tokenizer
+ - __call__
+ - save_vocabulary
+ - decode
+ - batch_decode
+
+## SpeechT5FeatureExtractor
+
+[[autodoc]] SpeechT5FeatureExtractor
+ - __call__
+
+## SpeechT5Processor
+
+[[autodoc]] SpeechT5Processor
+ - __call__
+ - pad
+ - from_pretrained
+ - save_pretrained
+ - batch_decode
+ - decode
+
+## SpeechT5Model
+
+[[autodoc]] SpeechT5Model
+ - forward
+
+## SpeechT5ForSpeechToText
+
+[[autodoc]] SpeechT5ForSpeechToText
+ - forward
+
+## SpeechT5ForTextToSpeech
+
+[[autodoc]] SpeechT5ForTextToSpeech
+ - forward
+ - generate
+
+## SpeechT5ForSpeechToSpeech
+
+[[autodoc]] SpeechT5ForSpeechToSpeech
+ - forward
+ - generate_speech
+
+## SpeechT5HifiGan
+
+[[autodoc]] SpeechT5HifiGan
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/splinter.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/splinter.md
new file mode 100644
index 0000000000000000000000000000000000000000..a46c55966c0ecf2bd6e0f6609e35fcd185e091bc
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/splinter.md
@@ -0,0 +1,87 @@
+
+
+# Splinter
+
+## Overview
+
+The Splinter model was proposed in [Few-Shot Question Answering by Pretraining Span Selection](https://arxiv.org/abs/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy. Splinter
+is an encoder-only transformer (similar to BERT) pretrained using the recurring span selection task on a large corpus
+comprising Wikipedia and the Toronto Book Corpus.
+
+The abstract from the paper is the following:
+
+In several question answering benchmarks, pretrained models have reached human parity through fine-tuning on an order
+of 100,000 annotated questions and answers. We explore the more realistic few-shot setting, where only a few hundred
+training examples are available, and observe that standard models perform poorly, highlighting the discrepancy between
+current pretraining objectives and question answering. We propose a new pretraining scheme tailored for question
+answering: recurring span selection. Given a passage with multiple sets of recurring spans, we mask in each set all
+recurring spans but one, and ask the model to select the correct span in the passage for each masked span. Masked spans
+are replaced with a special token, viewed as a question representation, that is later used during fine-tuning to select
+the answer span. The resulting model obtains surprisingly good results on multiple benchmarks (e.g., 72.7 F1 on SQuAD
+with only 128 training examples), while maintaining competitive performance in the high-resource setting.
+
+This model was contributed by [yuvalkirstain](https://huggingface.co/yuvalkirstain) and [oriram](https://huggingface.co/oriram). The original code can be found [here](https://github.com/oriram/splinter).
+
+## Usage tips
+
+- Splinter was trained to predict answers spans conditioned on a special [QUESTION] token. These tokens contextualize
+ to question representations which are used to predict the answers. This layer is called QASS, and is the default
+ behaviour in the [`SplinterForQuestionAnswering`] class. Therefore:
+- Use [`SplinterTokenizer`] (rather than [`BertTokenizer`]), as it already
+ contains this special token. Also, its default behavior is to use this token when two sequences are given (for
+ example, in the *run_qa.py* script).
+- If you plan on using Splinter outside *run_qa.py*, please keep in mind the question token - it might be important for
+ the success of your model, especially in a few-shot setting.
+- Please note there are two different checkpoints for each size of Splinter. Both are basically the same, except that
+ one also has the pretrained weights of the QASS layer (*tau/splinter-base-qass* and *tau/splinter-large-qass*) and one
+ doesn't (*tau/splinter-base* and *tau/splinter-large*). This is done to support randomly initializing this layer at
+ fine-tuning, as it is shown to yield better results for some cases in the paper.
+
+## Resources
+
+- [Question answering task guide](../tasks/question-answering)
+
+## SplinterConfig
+
+[[autodoc]] SplinterConfig
+
+## SplinterTokenizer
+
+[[autodoc]] SplinterTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## SplinterTokenizerFast
+
+[[autodoc]] SplinterTokenizerFast
+
+## SplinterModel
+
+[[autodoc]] SplinterModel
+ - forward
+
+## SplinterForQuestionAnswering
+
+[[autodoc]] SplinterForQuestionAnswering
+ - forward
+
+## SplinterForPreTraining
+
+[[autodoc]] SplinterForPreTraining
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/squeezebert.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/squeezebert.md
new file mode 100644
index 0000000000000000000000000000000000000000..e2bb378fe5bb093b900519d9d818376d265264a9
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/squeezebert.md
@@ -0,0 +1,99 @@
+
+
+# SqueezeBERT
+
+## Overview
+
+The SqueezeBERT model was proposed in [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://arxiv.org/abs/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, Kurt W. Keutzer. It's a
+bidirectional transformer similar to the BERT model. The key difference between the BERT architecture and the
+SqueezeBERT architecture is that SqueezeBERT uses [grouped convolutions](https://blog.yani.io/filter-group-tutorial)
+instead of fully-connected layers for the Q, K, V and FFN layers.
+
+The abstract from the paper is the following:
+
+*Humans read and write hundreds of billions of messages every day. Further, due to the availability of large datasets,
+large computing systems, and better neural network models, natural language processing (NLP) technology has made
+significant strides in understanding, proofreading, and organizing these messages. Thus, there is a significant
+opportunity to deploy NLP in myriad applications to help web users, social networks, and businesses. In particular, we
+consider smartphones and other mobile devices as crucial platforms for deploying NLP models at scale. However, today's
+highly-accurate NLP neural network models such as BERT and RoBERTa are extremely computationally expensive, with
+BERT-base taking 1.7 seconds to classify a text snippet on a Pixel 3 smartphone. In this work, we observe that methods
+such as grouped convolutions have yielded significant speedups for computer vision networks, but many of these
+techniques have not been adopted by NLP neural network designers. We demonstrate how to replace several operations in
+self-attention layers with grouped convolutions, and we use this technique in a novel network architecture called
+SqueezeBERT, which runs 4.3x faster than BERT-base on the Pixel 3 while achieving competitive accuracy on the GLUE test
+set. The SqueezeBERT code will be released.*
+
+This model was contributed by [forresti](https://huggingface.co/forresti).
+
+## Usage tips
+
+- SqueezeBERT is a model with absolute position embeddings so it's usually advised to pad the inputs on the right
+ rather than the left.
+- SqueezeBERT is similar to BERT and therefore relies on the masked language modeling (MLM) objective. It is therefore
+ efficient at predicting masked tokens and at NLU in general, but is not optimal for text generation. Models trained
+ with a causal language modeling (CLM) objective are better in that regard.
+- For best results when finetuning on sequence classification tasks, it is recommended to start with the
+ *squeezebert/squeezebert-mnli-headless* checkpoint.
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## SqueezeBertConfig
+
+[[autodoc]] SqueezeBertConfig
+
+## SqueezeBertTokenizer
+
+[[autodoc]] SqueezeBertTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## SqueezeBertTokenizerFast
+
+[[autodoc]] SqueezeBertTokenizerFast
+
+## SqueezeBertModel
+
+[[autodoc]] SqueezeBertModel
+
+## SqueezeBertForMaskedLM
+
+[[autodoc]] SqueezeBertForMaskedLM
+
+## SqueezeBertForSequenceClassification
+
+[[autodoc]] SqueezeBertForSequenceClassification
+
+## SqueezeBertForMultipleChoice
+
+[[autodoc]] SqueezeBertForMultipleChoice
+
+## SqueezeBertForTokenClassification
+
+[[autodoc]] SqueezeBertForTokenClassification
+
+## SqueezeBertForQuestionAnswering
+
+[[autodoc]] SqueezeBertForQuestionAnswering
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/stablelm.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/stablelm.md
new file mode 100644
index 0000000000000000000000000000000000000000..09c0e5855c3a1df8fd5e91212e9aca0e54fb3e6d
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/stablelm.md
@@ -0,0 +1,111 @@
+
+
+# StableLM
+
+## Overview
+
+`StableLM 3B 4E1T` was proposed in [`StableLM 3B 4E1T`: Technical Report](https://stability.wandb.io/stability-llm/stable-lm/reports/StableLM-3B-4E1T--VmlldzoyMjU4?accessToken=u3zujipenkx5g7rtcj9qojjgxpconyjktjkli2po09nffrffdhhchq045vp0wyfo) by Stability AI and is the first model in a series of multi-epoch pre-trained language models.
+
+### Model Details
+
+`StableLM 3B 4E1T` is a decoder-only base language model pre-trained on 1 trillion tokens of diverse English and code datasets for four epochs.
+The model architecture is transformer-based with partial Rotary Position Embeddings, SwiGLU activation, LayerNorm, etc.
+
+We also provide `StableLM Zephyr 3B`, an instruction fine-tuned version of the model that can be used for chat-based applications.
+
+### Usage Tips
+
+- The architecture is similar to LLaMA but with RoPE applied to 25% of head embedding dimensions, LayerNorm instead of RMSNorm, and optional QKV bias terms.
+- `StableLM 3B 4E1T`-based models uses the same tokenizer as [`GPTNeoXTokenizerFast`].
+
+`StableLM 3B 4E1T` and `StableLM Zephyr 3B` can be found on the [Huggingface Hub](https://huggingface.co/stabilityai)
+
+The following code snippet demonstrates how to use `StableLM 3B 4E1T` for inference:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, set_seed
+>>> device = "cuda" # the device to load the model onto
+
+>>> set_seed(0)
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stabilityai/stablelm-3b-4e1t")
+>>> model = AutoModelForCausalLM.from_pretrained("stabilityai/stablelm-3b-4e1t")
+>>> model.to(device) # doctest: +IGNORE_RESULT
+
+>>> model_inputs = tokenizer("The weather is always wonderful in", return_tensors="pt").to(model.device)
+
+>>> generated_ids = model.generate(**model_inputs, max_length=32, do_sample=True)
+>>> responses = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+>>> responses
+['The weather is always wonderful in Costa Rica, which makes it a prime destination for retirees. That’s where the Pensionado program comes in, offering']
+```
+
+## Combining StableLM and Flash Attention 2
+
+First, make sure to install the latest version of Flash Attention v2.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Also make sure that your hardware is compatible with Flash-Attention 2. Read more about it in the official documentation of the [`flash-attn`](https://github.com/Dao-AILab/flash-attention) repository. Note: you must load your model in half-precision (e.g. `torch.bfloat16`).
+
+Now, to run the model with Flash Attention 2, refer to the snippet below:
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, set_seed
+>>> device = "cuda" # the device to load the model onto
+
+>>> set_seed(0)
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stabilityai/stablelm-3b-4e1t")
+>>> model = AutoModelForCausalLM.from_pretrained("stabilityai/stablelm-3b-4e1t", torch_dtype=torch.bfloat16, attn_implementation="flash_attention_2") # doctest: +SKIP
+>>> model.to(device) # doctest: +SKIP
+
+>>> model_inputs = tokenizer("The weather is always wonderful in", return_tensors="pt").to(model.device)
+
+>>> generated_ids = model.generate(**model_inputs, max_length=32, do_sample=True) # doctest: +SKIP
+>>> responses = tokenizer.batch_decode(generated_ids, skip_special_tokens=True) # doctest: +SKIP
+>>> responses # doctest: +SKIP
+['The weather is always wonderful in Costa Rica, which makes it a prime destination for retirees. That’s where the Pensionado program comes in, offering']
+```
+
+
+## StableLmConfig
+
+[[autodoc]] StableLmConfig
+
+## StableLmModel
+
+[[autodoc]] StableLmModel
+ - forward
+
+## StableLmForCausalLM
+
+[[autodoc]] StableLmForCausalLM
+ - forward
+
+## StableLmForSequenceClassification
+
+[[autodoc]] StableLmForSequenceClassification
+ - forward
+
+## StableLmForTokenClassification
+
+[[autodoc]] StableLmForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/starcoder2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/starcoder2.md
new file mode 100644
index 0000000000000000000000000000000000000000..1d107b3855564ac90e4e47241de0c06e9f5fa882
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/starcoder2.md
@@ -0,0 +1,73 @@
+
+
+# Starcoder2
+
+## Overview
+
+StarCoder2 is a family of open LLMs for code and comes in 3 different sizes with 3B, 7B and 15B parameters. The flagship StarCoder2-15B model is trained on over 4 trillion tokens and 600+ programming languages from The Stack v2. All models use Grouped Query Attention, a context window of 16,384 tokens with a sliding window attention of 4,096 tokens, and were trained using the Fill-in-the-Middle objective. The models have been released with the paper [StarCoder 2 and The Stack v2: The Next Generation](https://arxiv.org/abs/2402.19173) by Anton Lozhkov, Raymond Li, Loubna Ben Allal, Federico Cassano, Joel Lamy-Poirier, Nouamane Tazi, Ao Tang, Dmytro Pykhtar, Jiawei Liu, Yuxiang Wei, Tianyang Liu, Max Tian, Denis Kocetkov, Arthur Zucker, Younes Belkada, Zijian Wang, Qian Liu, Dmitry Abulkhanov, Indraneil Paul, Zhuang Li, Wen-Ding Li, Megan Risdal, Jia Li, Jian Zhu, Terry Yue Zhuo, Evgenii Zheltonozhskii, Nii Osae Osae Dade, Wenhao Yu, Lucas Krauß, Naman Jain, Yixuan Su, Xuanli He, Manan Dey, Edoardo Abati, Yekun Chai, Niklas Muennighoff, Xiangru Tang, Muhtasham Oblokulov, Christopher Akiki, Marc Marone, Chenghao Mou, Mayank Mishra, Alex Gu, Binyuan Hui, Tri Dao, Armel Zebaze, Olivier Dehaene, Nicolas Patry, Canwen Xu, Julian McAuley, Han Hu, Torsten Scholak, Sebastien Paquet, Jennifer Robinson, Carolyn Jane Anderson, Nicolas Chapados, Mostofa Patwary, Nima Tajbakhsh, Yacine Jernite, Carlos Muñoz Ferrandis, Lingming Zhang, Sean Hughes, Thomas Wolf, Arjun Guha, Leandro von Werra, and Harm de Vries.
+
+The abstract of the paper is the following:
+
+> The BigCode project, an open-scientific collaboration focused on the responsible development of Large Language Models for Code (Code LLMs), introduces StarCoder2. In partnership with Software Heritage (SWH), we build The Stack v2 on top of the digital commons of their source code archive. Alongside the SWH repositories spanning 619 programming languages, we carefully select other high-quality data sources, such as GitHub pull requests, Kaggle notebooks, and code documentation. This results in a training set that is 4x larger than the first StarCoder dataset. We train StarCoder2 models with 3B, 7B, and 15B parameters on 3.3 to 4.3 trillion tokens and thoroughly evaluate them on a comprehensive set of Code LLM benchmarks. We find that our small model, StarCoder2-3B, outperforms other Code LLMs of similar size on most benchmarks, and also outperforms StarCoderBase-15B. Our large model, StarCoder2- 15B, significantly outperforms other models of comparable size. In addition, it matches or outperforms CodeLlama-34B, a model more than twice its size. Although DeepSeekCoder- 33B is the best-performing model at code completion for high-resource languages, we find that StarCoder2-15B outperforms it on math and code reasoning benchmarks, as well as several low-resource languages. We make the model weights available under an OpenRAIL license and ensure full transparency regarding the training data by releasing the SoftWare Heritage persistent IDentifiers (SWHIDs) of the source code data.
+## License
+
+The models are licensed under the [BigCode OpenRAIL-M v1 license agreement](https://huggingface.co/spaces/bigcode/bigcode-model-license-agreement).
+
+## Usage tips
+
+The StarCoder2 models can be found in the [HuggingFace hub](https://huggingface.co/collections/bigcode/starcoder2-65de6da6e87db3383572be1a). You can find some examples for inference and fine-tuning in StarCoder2's [GitHub repo](https://github.com/bigcode-project/starcoder2).
+
+These ready-to-use checkpoints can be downloaded and used via the HuggingFace Hub:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("bigcode/starcoder2-7b", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("bigcode/starcoder2-7b")
+
+>>> prompt = "def print_hello_world():"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to("cuda")
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=10, do_sample=False)
+>>> tokenizer.batch_decode(generated_ids)[0]
+'def print_hello_world():\n print("Hello World!")\n\ndef print'
+```
+
+## Starcoder2Config
+
+[[autodoc]] Starcoder2Config
+
+## Starcoder2Model
+
+[[autodoc]] Starcoder2Model
+ - forward
+
+## Starcoder2ForCausalLM
+
+[[autodoc]] Starcoder2ForCausalLM
+ - forward
+
+## Starcoder2ForSequenceClassification
+
+[[autodoc]] Starcoder2ForSequenceClassification
+ - forward
+
+## Starcoder2ForTokenClassification
+
+[[autodoc]] Starcoder2ForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/superpoint.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/superpoint.md
new file mode 100644
index 0000000000000000000000000000000000000000..59e451adceb8173b2577ba752ca2d2502d54d878
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/superpoint.md
@@ -0,0 +1,140 @@
+
+
+# SuperPoint
+
+## Overview
+
+The SuperPoint model was proposed
+in [SuperPoint: Self-Supervised Interest Point Detection and Description](https://arxiv.org/abs/1712.07629) by Daniel
+DeTone, Tomasz Malisiewicz and Andrew Rabinovich.
+
+This model is the result of a self-supervised training of a fully-convolutional network for interest point detection and
+description. The model is able to detect interest points that are repeatable under homographic transformations and
+provide a descriptor for each point. The use of the model in its own is limited, but it can be used as a feature
+extractor for other tasks such as homography estimation, image matching, etc.
+
+The abstract from the paper is the following:
+
+*This paper presents a self-supervised framework for training interest point detectors and descriptors suitable for a
+large number of multiple-view geometry problems in computer vision. As opposed to patch-based neural networks, our
+fully-convolutional model operates on full-sized images and jointly computes pixel-level interest point locations and
+associated descriptors in one forward pass. We introduce Homographic Adaptation, a multi-scale, multi-homography
+approach for boosting interest point detection repeatability and performing cross-domain adaptation (e.g.,
+synthetic-to-real). Our model, when trained on the MS-COCO generic image dataset using Homographic Adaptation, is able
+to repeatedly detect a much richer set of interest points than the initial pre-adapted deep model and any other
+traditional corner detector. The final system gives rise to state-of-the-art homography estimation results on HPatches
+when compared to LIFT, SIFT and ORB.*
+
+
+
+ SuperPoint overview. Taken from the original paper.
+
+## Usage tips
+
+Here is a quick example of using the model to detect interest points in an image:
+
+```python
+from transformers import AutoImageProcessor, SuperPointForKeypointDetection
+import torch
+from PIL import Image
+import requests
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+processor = AutoImageProcessor.from_pretrained("magic-leap-community/superpoint")
+model = SuperPointForKeypointDetection.from_pretrained("magic-leap-community/superpoint")
+
+inputs = processor(image, return_tensors="pt")
+outputs = model(**inputs)
+```
+
+The outputs contain the list of keypoint coordinates with their respective score and description (a 256-long vector).
+
+You can also feed multiple images to the model. Due to the nature of SuperPoint, to output a dynamic number of keypoints,
+you will need to use the mask attribute to retrieve the respective information :
+
+```python
+from transformers import AutoImageProcessor, SuperPointForKeypointDetection
+import torch
+from PIL import Image
+import requests
+
+url_image_1 = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image_1 = Image.open(requests.get(url_image_1, stream=True).raw)
+url_image_2 = "http://images.cocodataset.org/test-stuff2017/000000000568.jpg"
+image_2 = Image.open(requests.get(url_image_2, stream=True).raw)
+
+images = [image_1, image_2]
+
+processor = AutoImageProcessor.from_pretrained("magic-leap-community/superpoint")
+model = SuperPointForKeypointDetection.from_pretrained("magic-leap-community/superpoint")
+
+inputs = processor(images, return_tensors="pt")
+outputs = model(**inputs)
+image_sizes = [(image.height, image.width) for image in images]
+outputs = processor.post_process_keypoint_detection(outputs, image_sizes)
+
+for output in outputs:
+ for keypoints, scores, descriptors in zip(output["keypoints"], output["scores"], output["descriptors"]):
+ print(f"Keypoints: {keypoints}")
+ print(f"Scores: {scores}")
+ print(f"Descriptors: {descriptors}")
+```
+
+You can then print the keypoints on the image of your choice to visualize the result:
+```python
+import matplotlib.pyplot as plt
+
+plt.axis("off")
+plt.imshow(image_1)
+plt.scatter(
+ outputs[0]["keypoints"][:, 0],
+ outputs[0]["keypoints"][:, 1],
+ c=outputs[0]["scores"] * 100,
+ s=outputs[0]["scores"] * 50,
+ alpha=0.8
+)
+plt.savefig(f"output_image.png")
+```
+
+
+This model was contributed by [stevenbucaille](https://huggingface.co/stevenbucaille).
+The original code can be found [here](https://github.com/magicleap/SuperPointPretrainedNetwork).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with SuperPoint. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- A notebook showcasing inference and visualization with SuperPoint can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/SuperPoint/Inference_with_SuperPoint_to_detect_interest_points_in_an_image.ipynb). 🌎
+
+## SuperPointConfig
+
+[[autodoc]] SuperPointConfig
+
+## SuperPointImageProcessor
+
+[[autodoc]] SuperPointImageProcessor
+
+- preprocess
+- post_process_keypoint_detection
+
+## SuperPointForKeypointDetection
+
+[[autodoc]] SuperPointForKeypointDetection
+
+- forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swiftformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swiftformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..319c79fce4fbece5b557dd0f03d688174fbf5043
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swiftformer.md
@@ -0,0 +1,54 @@
+
+
+# SwiftFormer
+
+## Overview
+
+The SwiftFormer model was proposed in [SwiftFormer: Efficient Additive Attention for Transformer-based Real-time Mobile Vision Applications](https://arxiv.org/abs/2303.15446) by Abdelrahman Shaker, Muhammad Maaz, Hanoona Rasheed, Salman Khan, Ming-Hsuan Yang, Fahad Shahbaz Khan.
+
+The SwiftFormer paper introduces a novel efficient additive attention mechanism that effectively replaces the quadratic matrix multiplication operations in the self-attention computation with linear element-wise multiplications. A series of models called 'SwiftFormer' is built based on this, which achieves state-of-the-art performance in terms of both accuracy and mobile inference speed. Even their small variant achieves 78.5% top-1 ImageNet1K accuracy with only 0.8 ms latency on iPhone 14, which is more accurate and 2× faster compared to MobileViT-v2.
+
+The abstract from the paper is the following:
+
+*Self-attention has become a defacto choice for capturing global context in various vision applications. However, its quadratic computational complexity with respect to image resolution limits its use in real-time applications, especially for deployment on resource-constrained mobile devices. Although hybrid approaches have been proposed to combine the advantages of convolutions and self-attention for a better speed-accuracy trade-off, the expensive matrix multiplication operations in self-attention remain a bottleneck. In this work, we introduce a novel efficient additive attention mechanism that effectively replaces the quadratic matrix multiplication operations with linear element-wise multiplications. Our design shows that the key-value interaction can be replaced with a linear layer without sacrificing any accuracy. Unlike previous state-of-the-art methods, our efficient formulation of self-attention enables its usage at all stages of the network. Using our proposed efficient additive attention, we build a series of models called "SwiftFormer" which achieves state-of-the-art performance in terms of both accuracy and mobile inference speed. Our small variant achieves 78.5% top-1 ImageNet-1K accuracy with only 0.8 ms latency on iPhone 14, which is more accurate and 2x faster compared to MobileViT-v2.*
+
+This model was contributed by [shehan97](https://huggingface.co/shehan97). The TensorFlow version was contributed by [joaocmd](https://huggingface.co/joaocmd).
+The original code can be found [here](https://github.com/Amshaker/SwiftFormer).
+
+## SwiftFormerConfig
+
+[[autodoc]] SwiftFormerConfig
+
+## SwiftFormerModel
+
+[[autodoc]] SwiftFormerModel
+ - forward
+
+## SwiftFormerForImageClassification
+
+[[autodoc]] SwiftFormerForImageClassification
+ - forward
+
+## TFSwiftFormerModel
+
+[[autodoc]] TFSwiftFormerModel
+ - call
+
+## TFSwiftFormerForImageClassification
+
+[[autodoc]] TFSwiftFormerForImageClassification
+ - call
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swin.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swin.md
new file mode 100644
index 0000000000000000000000000000000000000000..e23c882a3f097aef0bcc3e04469ed0a3104be982
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swin.md
@@ -0,0 +1,107 @@
+
+
+# Swin Transformer
+
+## Overview
+
+The Swin Transformer was proposed in [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030)
+by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
+
+The abstract from the paper is the following:
+
+*This paper presents a new vision Transformer, called Swin Transformer, that capably serves as a general-purpose backbone
+for computer vision. Challenges in adapting Transformer from language to vision arise from differences between the two domains,
+such as large variations in the scale of visual entities and the high resolution of pixels in images compared to words in text.
+To address these differences, we propose a hierarchical Transformer whose representation is computed with \bold{S}hifted
+\bold{win}dows. The shifted windowing scheme brings greater efficiency by limiting self-attention computation to non-overlapping
+local windows while also allowing for cross-window connection. This hierarchical architecture has the flexibility to model at
+various scales and has linear computational complexity with respect to image size. These qualities of Swin Transformer make it
+compatible with a broad range of vision tasks, including image classification (87.3 top-1 accuracy on ImageNet-1K) and dense
+prediction tasks such as object detection (58.7 box AP and 51.1 mask AP on COCO test-dev) and semantic segmentation
+(53.5 mIoU on ADE20K val). Its performance surpasses the previous state-of-the-art by a large margin of +2.7 box AP and
++2.6 mask AP on COCO, and +3.2 mIoU on ADE20K, demonstrating the potential of Transformer-based models as vision backbones.
+The hierarchical design and the shifted window approach also prove beneficial for all-MLP architectures.*
+
+
+
+ Swin Transformer architecture. Taken from the original paper.
+
+This model was contributed by [novice03](https://huggingface.co/novice03). The Tensorflow version of this model was contributed by [amyeroberts](https://huggingface.co/amyeroberts). The original code can be found [here](https://github.com/microsoft/Swin-Transformer).
+
+## Usage tips
+
+- Swin pads the inputs supporting any input height and width (if divisible by `32`).
+- Swin can be used as a *backbone*. When `output_hidden_states = True`, it will output both `hidden_states` and `reshaped_hidden_states`. The `reshaped_hidden_states` have a shape of `(batch, num_channels, height, width)` rather than `(batch_size, sequence_length, num_channels)`.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Swin Transformer.
+
+
+
+- [`SwinForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+Besides that:
+
+- [`SwinForMaskedImageModeling`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## SwinConfig
+
+[[autodoc]] SwinConfig
+
+
+
+
+## SwinModel
+
+[[autodoc]] SwinModel
+ - forward
+
+## SwinForMaskedImageModeling
+
+[[autodoc]] SwinForMaskedImageModeling
+ - forward
+
+## SwinForImageClassification
+
+[[autodoc]] transformers.SwinForImageClassification
+ - forward
+
+
+
+
+## TFSwinModel
+
+[[autodoc]] TFSwinModel
+ - call
+
+## TFSwinForMaskedImageModeling
+
+[[autodoc]] TFSwinForMaskedImageModeling
+ - call
+
+## TFSwinForImageClassification
+
+[[autodoc]] transformers.TFSwinForImageClassification
+ - call
+
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swin2sr.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swin2sr.md
new file mode 100644
index 0000000000000000000000000000000000000000..18d6635feffce2b968cbd2d2f5061801773d1bad
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swin2sr.md
@@ -0,0 +1,61 @@
+
+
+# Swin2SR
+
+## Overview
+
+The Swin2SR model was proposed in [Swin2SR: SwinV2 Transformer for Compressed Image Super-Resolution and Restoration](https://arxiv.org/abs/2209.11345) by Marcos V. Conde, Ui-Jin Choi, Maxime Burchi, Radu Timofte.
+Swin2SR improves the [SwinIR](https://github.com/JingyunLiang/SwinIR/) model by incorporating [Swin Transformer v2](swinv2) layers which mitigates issues such as training instability, resolution gaps between pre-training
+and fine-tuning, and hunger on data.
+
+The abstract from the paper is the following:
+
+*Compression plays an important role on the efficient transmission and storage of images and videos through band-limited systems such as streaming services, virtual reality or videogames. However, compression unavoidably leads to artifacts and the loss of the original information, which may severely degrade the visual quality. For these reasons, quality enhancement of compressed images has become a popular research topic. While most state-of-the-art image restoration methods are based on convolutional neural networks, other transformers-based methods such as SwinIR, show impressive performance on these tasks.
+In this paper, we explore the novel Swin Transformer V2, to improve SwinIR for image super-resolution, and in particular, the compressed input scenario. Using this method we can tackle the major issues in training transformer vision models, such as training instability, resolution gaps between pre-training and fine-tuning, and hunger on data. We conduct experiments on three representative tasks: JPEG compression artifacts removal, image super-resolution (classical and lightweight), and compressed image super-resolution. Experimental results demonstrate that our method, Swin2SR, can improve the training convergence and performance of SwinIR, and is a top-5 solution at the "AIM 2022 Challenge on Super-Resolution of Compressed Image and Video".*
+
+
+
+ Swin2SR architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/mv-lab/swin2sr).
+
+## Resources
+
+Demo notebooks for Swin2SR can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Swin2SR).
+
+A demo Space for image super-resolution with SwinSR can be found [here](https://huggingface.co/spaces/jjourney1125/swin2sr).
+
+## Swin2SRImageProcessor
+
+[[autodoc]] Swin2SRImageProcessor
+ - preprocess
+
+## Swin2SRConfig
+
+[[autodoc]] Swin2SRConfig
+
+## Swin2SRModel
+
+[[autodoc]] Swin2SRModel
+ - forward
+
+## Swin2SRForImageSuperResolution
+
+[[autodoc]] Swin2SRForImageSuperResolution
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swinv2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swinv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..25233dca33954554c92f177fe076a779e99f0be6
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swinv2.md
@@ -0,0 +1,62 @@
+
+
+# Swin Transformer V2
+
+## Overview
+
+The Swin Transformer V2 model was proposed in [Swin Transformer V2: Scaling Up Capacity and Resolution](https://arxiv.org/abs/2111.09883) by Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo.
+
+The abstract from the paper is the following:
+
+*Large-scale NLP models have been shown to significantly improve the performance on language tasks with no signs of saturation. They also demonstrate amazing few-shot capabilities like that of human beings. This paper aims to explore large-scale models in computer vision. We tackle three major issues in training and application of large vision models, including training instability, resolution gaps between pre-training and fine-tuning, and hunger on labelled data. Three main techniques are proposed: 1) a residual-post-norm method combined with cosine attention to improve training stability; 2) A log-spaced continuous position bias method to effectively transfer models pre-trained using low-resolution images to downstream tasks with high-resolution inputs; 3) A self-supervised pre-training method, SimMIM, to reduce the needs of vast labeled images. Through these techniques, this paper successfully trained a 3 billion-parameter Swin Transformer V2 model, which is the largest dense vision model to date, and makes it capable of training with images of up to 1,536×1,536 resolution. It set new performance records on 4 representative vision tasks, including ImageNet-V2 image classification, COCO object detection, ADE20K semantic segmentation, and Kinetics-400 video action classification. Also note our training is much more efficient than that in Google's billion-level visual models, which consumes 40 times less labelled data and 40 times less training time.*
+
+This model was contributed by [nandwalritik](https://huggingface.co/nandwalritik).
+The original code can be found [here](https://github.com/microsoft/Swin-Transformer).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Swin Transformer v2.
+
+
+
+- [`Swinv2ForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+Besides that:
+
+- [`Swinv2ForMaskedImageModeling`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## Swinv2Config
+
+[[autodoc]] Swinv2Config
+
+## Swinv2Model
+
+[[autodoc]] Swinv2Model
+ - forward
+
+## Swinv2ForMaskedImageModeling
+
+[[autodoc]] Swinv2ForMaskedImageModeling
+ - forward
+
+## Swinv2ForImageClassification
+
+[[autodoc]] transformers.Swinv2ForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/switch_transformers.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/switch_transformers.md
new file mode 100644
index 0000000000000000000000000000000000000000..ca6748167f5e014f32448b3b62e0f5050f08ce1d
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/switch_transformers.md
@@ -0,0 +1,71 @@
+
+
+# SwitchTransformers
+
+## Overview
+
+The SwitchTransformers model was proposed in [Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity](https://arxiv.org/abs/2101.03961) by William Fedus, Barret Zoph, Noam Shazeer.
+
+The Switch Transformer model uses a sparse T5 encoder-decoder architecture, where the MLP are replaced by a Mixture of Experts (MoE). A routing mechanism (top 1 in this case) associates each token to one of the expert, where each expert is a dense MLP. While switch transformers have a lot more weights than their equivalent dense models, the sparsity allows better scaling and better finetuning performance at scale.
+During a forward pass, only a fraction of the weights are used. The routing mechanism allows the model to select relevant weights on the fly which increases the model capacity without increasing the number of operations.
+
+The abstract from the paper is the following:
+
+*In deep learning, models typically reuse the same parameters for all inputs. Mixture of Experts (MoE) defies this and instead selects different parameters for each incoming example. The result is a sparsely-activated model -- with outrageous numbers of parameters -- but a constant computational cost. However, despite several notable successes of MoE, widespread adoption has been hindered by complexity, communication costs and training instability -- we address these with the Switch Transformer. We simplify the MoE routing algorithm and design intuitive improved models with reduced communication and computational costs. Our proposed training techniques help wrangle the instabilities and we show large sparse models may be trained, for the first time, with lower precision (bfloat16) formats. We design models based off T5-Base and T5-Large to obtain up to 7x increases in pre-training speed with the same computational resources. These improvements extend into multilingual settings where we measure gains over the mT5-Base version across all 101 languages. Finally, we advance the current scale of language models by pre-training up to trillion parameter models on the "Colossal Clean Crawled Corpus" and achieve a 4x speedup over the T5-XXL model.*
+
+This model was contributed by [Younes Belkada](https://huggingface.co/ybelkada) and [Arthur Zucker](https://huggingface.co/ArthurZ).
+The original code can be found [here](https://github.com/google/flaxformer/tree/main/flaxformer/architectures/moe).
+
+## Usage tips
+
+- SwitchTransformers uses the [`T5Tokenizer`], which can be loaded directly from each model's repository.
+- The released weights are pretrained on English [Masked Language Modeling](https://moon-ci-docs.huggingface.co/docs/transformers/pr_19323/en/glossary#general-terms) task, and should be finetuned.
+
+## Resources
+
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## SwitchTransformersConfig
+
+[[autodoc]] SwitchTransformersConfig
+
+## SwitchTransformersTop1Router
+
+[[autodoc]] SwitchTransformersTop1Router
+ - _compute_router_probabilities
+ - forward
+
+## SwitchTransformersSparseMLP
+
+[[autodoc]] SwitchTransformersSparseMLP
+ - forward
+
+## SwitchTransformersModel
+
+[[autodoc]] SwitchTransformersModel
+ - forward
+
+## SwitchTransformersForConditionalGeneration
+
+[[autodoc]] SwitchTransformersForConditionalGeneration
+ - forward
+
+## SwitchTransformersEncoderModel
+
+[[autodoc]] SwitchTransformersEncoderModel
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/t5.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/t5.md
new file mode 100644
index 0000000000000000000000000000000000000000..86a645512c6cde8a02c6f81eb2d61a91c0d037dd
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/t5.md
@@ -0,0 +1,456 @@
+
+
+# T5
+
+
+
+## Overview
+
+The T5 model was presented in [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/pdf/1910.10683.pdf) by [Colin Raffel](https://huggingface.co/craffel), Noam Shazeer, [Adam Roberts](https://huggingface.co/adarob), Katherine Lee, Sharan Narang,
+Michael Matena, Yanqi Zhou, Wei Li, [Peter J. Liu](https://huggingface.co/peterjliu).
+
+The abstract from the paper is the following:
+
+*Transfer learning, where a model is first pre-trained on a data-rich task before being fine-tuned on a downstream
+task, has emerged as a powerful technique in natural language processing (NLP). The effectiveness of transfer learning
+has given rise to a diversity of approaches, methodology, and practice. In this paper, we explore the landscape of
+transfer learning techniques for NLP by introducing a unified framework that converts every language problem into a
+text-to-text format. Our systematic study compares pretraining objectives, architectures, unlabeled datasets, transfer
+approaches, and other factors on dozens of language understanding tasks. By combining the insights from our exploration
+with scale and our new "Colossal Clean Crawled Corpus", we achieve state-of-the-art results on many benchmarks covering
+summarization, question answering, text classification, and more. To facilitate future work on transfer learning for
+NLP, we release our dataset, pre-trained models, and code.*
+
+All checkpoints can be found on the [hub](https://huggingface.co/models?search=t5).
+
+This model was contributed by [thomwolf](https://huggingface.co/thomwolf). The original code can be found [here](https://github.com/google-research/text-to-text-transfer-transformer).
+
+## Usage tips
+
+- T5 is an encoder-decoder model pre-trained on a multi-task mixture of unsupervised and supervised tasks and for which
+each task is converted into a text-to-text format. T5 works well on a variety of tasks out-of-the-box by prepending a
+different prefix to the input corresponding to each task, e.g., for translation: *translate English to German: ...*,
+for summarization: *summarize: ...*.
+- The pretraining includes both supervised and self-supervised training. Supervised training is conducted on downstream tasks provided by the GLUE and SuperGLUE benchmarks (converting them into text-to-text tasks as explained above).
+- Self-supervised training uses corrupted tokens, by randomly removing 15% of the tokens and replacing them with individual sentinel tokens (if several consecutive tokens are marked for removal, the whole group is replaced with a single sentinel token). The input of the encoder is the corrupted sentence, the input of the decoder is the original sentence and the target is then the dropped out tokens delimited by their sentinel tokens.
+
+- T5 uses relative scalar embeddings. Encoder input padding can be done on the left and on the right.
+
+- See the [training](#training), [inference](#inference) and [resources](#resources) sections below for all details regarding usage.
+
+T5 comes in different sizes:
+
+- [google-t5/t5-small](https://huggingface.co/google-t5/t5-small)
+
+- [google-t5/t5-base](https://huggingface.co/google-t5/t5-base)
+
+- [google-t5/t5-large](https://huggingface.co/google-t5/t5-large)
+
+- [google-t5/t5-3b](https://huggingface.co/google-t5/t5-3b)
+
+- [google-t5/t5-11b](https://huggingface.co/google-t5/t5-11b).
+
+Based on the original T5 model, Google has released some follow-up works:
+
+- **T5v1.1**: T5v1.1 is an improved version of T5 with some architectural tweaks, and is pre-trained on C4 only without
+ mixing in the supervised tasks. Refer to the documentation of T5v1.1 which can be found [here](t5v1.1).
+
+- **mT5**: mT5 is a multilingual T5 model. It is pre-trained on the mC4 corpus, which includes 101 languages. Refer to
+ the documentation of mT5 which can be found [here](mt5).
+
+- **byT5**: byT5 is a T5 model pre-trained on byte sequences rather than SentencePiece subword token sequences. Refer
+ to the documentation of byT5 which can be found [here](byt5).
+
+- **UL2**: UL2 is a T5 like model pretrained on various denoising objectives
+
+- **Flan-T5**: Flan is a pretraining methods that is based on prompting. The Flan-T5 are T5 models trained on the Flan collection of
+ datasets which include: `taskmaster2`, `djaym7/wiki_dialog`, `deepmind/code_contests`, `lambada`, `gsm8k`, `aqua_rat`, `esnli`, `quasc` and `qed`.
+
+- **FLan-UL2** : the UL2 model finetuned using the "Flan" prompt tuning and dataset collection.
+
+- **UMT5**: UmT5 is a multilingual T5 model trained on an improved and refreshed mC4 multilingual corpus, 29 trillion characters across 107 language, using a new sampling method, UniMax. Refer to
+ the documentation of mT5 which can be found [here](umt5).
+
+## Training
+
+T5 is an encoder-decoder model and converts all NLP problems into a text-to-text format. It is trained using teacher
+forcing. This means that for training, we always need an input sequence and a corresponding target sequence. The input
+sequence is fed to the model using `input_ids`. The target sequence is shifted to the right, i.e., prepended by a
+start-sequence token and fed to the decoder using the `decoder_input_ids`. In teacher-forcing style, the target
+sequence is then appended by the EOS token and corresponds to the `labels`. The PAD token is hereby used as the
+start-sequence token. T5 can be trained / fine-tuned both in a supervised and unsupervised fashion.
+
+One can use [`T5ForConditionalGeneration`] (or the Tensorflow/Flax variant), which includes the
+language modeling head on top of the decoder.
+
+- Unsupervised denoising training
+
+In this setup, spans of the input sequence are masked by so-called sentinel tokens (*a.k.a* unique mask tokens) and
+the output sequence is formed as a concatenation of the same sentinel tokens and the *real* masked tokens. Each
+sentinel token represents a unique mask token for this sentence and should start with ``,
+``, ... up to ``. As a default, 100 sentinel tokens are available in
+[`T5Tokenizer`].
+
+For instance, the sentence "The cute dog walks in the park" with the masks put on "cute dog" and "the" should be
+processed as follows:
+
+```python
+>>> from transformers import T5Tokenizer, T5ForConditionalGeneration
+
+>>> tokenizer = T5Tokenizer.from_pretrained("google-t5/t5-small")
+>>> model = T5ForConditionalGeneration.from_pretrained("google-t5/t5-small")
+
+>>> input_ids = tokenizer("The walks in park", return_tensors="pt").input_ids
+>>> labels = tokenizer(" cute dog the ", return_tensors="pt").input_ids
+
+>>> # the forward function automatically creates the correct decoder_input_ids
+>>> loss = model(input_ids=input_ids, labels=labels).loss
+>>> loss.item()
+3.7837
+```
+
+If you're interested in pre-training T5 on a new corpus, check out the [run_t5_mlm_flax.py](https://github.com/huggingface/transformers/tree/main/examples/flax/language-modeling) script in the Examples
+directory.
+
+- Supervised training
+
+In this setup, the input sequence and output sequence are a standard sequence-to-sequence input-output mapping.
+Suppose that we want to fine-tune the model for translation for example, and we have a training example: the input
+sequence "The house is wonderful." and output sequence "Das Haus ist wunderbar.", then they should be prepared for
+the model as follows:
+
+```python
+>>> from transformers import T5Tokenizer, T5ForConditionalGeneration
+
+>>> tokenizer = T5Tokenizer.from_pretrained("google-t5/t5-small")
+>>> model = T5ForConditionalGeneration.from_pretrained("google-t5/t5-small")
+
+>>> input_ids = tokenizer("translate English to German: The house is wonderful.", return_tensors="pt").input_ids
+>>> labels = tokenizer("Das Haus ist wunderbar.", return_tensors="pt").input_ids
+
+>>> # the forward function automatically creates the correct decoder_input_ids
+>>> loss = model(input_ids=input_ids, labels=labels).loss
+>>> loss.item()
+0.2542
+```
+
+As you can see, only 2 inputs are required for the model in order to compute a loss: `input_ids` (which are the
+`input_ids` of the encoded input sequence) and `labels` (which are the `input_ids` of the encoded
+target sequence). The model will automatically create the `decoder_input_ids` based on the `labels`, by
+shifting them one position to the right and prepending the `config.decoder_start_token_id`, which for T5 is
+equal to 0 (i.e. the id of the pad token). Also note the task prefix: we prepend the input sequence with 'translate
+English to German: ' before encoding it. This will help in improving the performance, as this task prefix was used
+during T5's pre-training.
+
+However, the example above only shows a single training example. In practice, one trains deep learning models in
+batches. This entails that we must pad/truncate examples to the same length. For encoder-decoder models, one
+typically defines a `max_source_length` and `max_target_length`, which determine the maximum length of the
+input and output sequences respectively (otherwise they are truncated). These should be carefully set depending on
+the task.
+
+In addition, we must make sure that padding token id's of the `labels` are not taken into account by the loss
+function. In PyTorch and Tensorflow, this can be done by replacing them with -100, which is the `ignore_index`
+of the `CrossEntropyLoss`. In Flax, one can use the `decoder_attention_mask` to ignore padded tokens from
+the loss (see the [Flax summarization script](https://github.com/huggingface/transformers/tree/main/examples/flax/summarization) for details). We also pass
+`attention_mask` as additional input to the model, which makes sure that padding tokens of the inputs are
+ignored. The code example below illustrates all of this.
+
+```python
+>>> from transformers import T5Tokenizer, T5ForConditionalGeneration
+>>> import torch
+
+>>> tokenizer = T5Tokenizer.from_pretrained("google-t5/t5-small")
+>>> model = T5ForConditionalGeneration.from_pretrained("google-t5/t5-small")
+
+>>> # the following 2 hyperparameters are task-specific
+>>> max_source_length = 512
+>>> max_target_length = 128
+
+>>> # Suppose we have the following 2 training examples:
+>>> input_sequence_1 = "Welcome to NYC"
+>>> output_sequence_1 = "Bienvenue à NYC"
+
+>>> input_sequence_2 = "HuggingFace is a company"
+>>> output_sequence_2 = "HuggingFace est une entreprise"
+
+>>> # encode the inputs
+>>> task_prefix = "translate English to French: "
+>>> input_sequences = [input_sequence_1, input_sequence_2]
+
+>>> encoding = tokenizer(
+... [task_prefix + sequence for sequence in input_sequences],
+... padding="longest",
+... max_length=max_source_length,
+... truncation=True,
+... return_tensors="pt",
+... )
+
+>>> input_ids, attention_mask = encoding.input_ids, encoding.attention_mask
+
+>>> # encode the targets
+>>> target_encoding = tokenizer(
+... [output_sequence_1, output_sequence_2],
+... padding="longest",
+... max_length=max_target_length,
+... truncation=True,
+... return_tensors="pt",
+... )
+>>> labels = target_encoding.input_ids
+
+>>> # replace padding token id's of the labels by -100 so it's ignored by the loss
+>>> labels[labels == tokenizer.pad_token_id] = -100
+
+>>> # forward pass
+>>> loss = model(input_ids=input_ids, attention_mask=attention_mask, labels=labels).loss
+>>> loss.item()
+0.188
+```
+
+Additional training tips:
+
+- T5 models need a slightly higher learning rate than the default one set in the `Trainer` when using the AdamW
+optimizer. Typically, 1e-4 and 3e-4 work well for most problems (classification, summarization, translation, question
+answering, question generation). Note that T5 was pre-trained using the AdaFactor optimizer.
+
+According to [this forum post](https://discuss.huggingface.co/t/t5-finetuning-tips/684), task prefixes matter when
+(1) doing multi-task training (2) your task is similar or related to one of the supervised tasks used in T5's
+pre-training mixture (see Appendix D of the [paper](https://arxiv.org/pdf/1910.10683.pdf) for the task prefixes
+used).
+
+If training on TPU, it is recommended to pad all examples of the dataset to the same length or make use of
+*pad_to_multiple_of* to have a small number of predefined bucket sizes to fit all examples in. Dynamically padding
+batches to the longest example is not recommended on TPU as it triggers a recompilation for every batch shape that is
+encountered during training thus significantly slowing down the training. only padding up to the longest example in a
+batch) leads to very slow training on TPU.
+
+## Inference
+
+At inference time, it is recommended to use [`~generation.GenerationMixin.generate`]. This
+method takes care of encoding the input and feeding the encoded hidden states via cross-attention layers to the decoder
+and auto-regressively generates the decoder output. Check out [this blog post](https://huggingface.co/blog/how-to-generate) to know all the details about generating text with Transformers.
+There's also [this blog post](https://huggingface.co/blog/encoder-decoder#encoder-decoder) which explains how
+generation works in general in encoder-decoder models.
+
+```python
+>>> from transformers import T5Tokenizer, T5ForConditionalGeneration
+
+>>> tokenizer = T5Tokenizer.from_pretrained("google-t5/t5-small")
+>>> model = T5ForConditionalGeneration.from_pretrained("google-t5/t5-small")
+
+>>> input_ids = tokenizer("translate English to German: The house is wonderful.", return_tensors="pt").input_ids
+>>> outputs = model.generate(input_ids)
+>>> print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+Das Haus ist wunderbar.
+```
+
+Note that T5 uses the `pad_token_id` as the `decoder_start_token_id`, so when doing generation without using
+[`~generation.GenerationMixin.generate`], make sure you start it with the `pad_token_id`.
+
+The example above only shows a single example. You can also do batched inference, like so:
+
+```python
+>>> from transformers import T5Tokenizer, T5ForConditionalGeneration
+
+>>> tokenizer = T5Tokenizer.from_pretrained("google-t5/t5-small")
+>>> model = T5ForConditionalGeneration.from_pretrained("google-t5/t5-small")
+
+>>> task_prefix = "translate English to German: "
+>>> # use different length sentences to test batching
+>>> sentences = ["The house is wonderful.", "I like to work in NYC."]
+
+>>> inputs = tokenizer([task_prefix + sentence for sentence in sentences], return_tensors="pt", padding=True)
+
+>>> output_sequences = model.generate(
+... input_ids=inputs["input_ids"],
+... attention_mask=inputs["attention_mask"],
+... do_sample=False, # disable sampling to test if batching affects output
+... )
+
+>>> print(tokenizer.batch_decode(output_sequences, skip_special_tokens=True))
+['Das Haus ist wunderbar.', 'Ich arbeite gerne in NYC.']
+```
+
+Because T5 has been trained with the span-mask denoising objective,
+it can be used to predict the sentinel (masked-out) tokens during inference.
+The predicted tokens will then be placed between the sentinel tokens.
+
+```python
+>>> from transformers import T5Tokenizer, T5ForConditionalGeneration
+
+>>> tokenizer = T5Tokenizer.from_pretrained("google-t5/t5-small")
+>>> model = T5ForConditionalGeneration.from_pretrained("google-t5/t5-small")
+
+>>> input_ids = tokenizer("The walks in park", return_tensors="pt").input_ids
+
+>>> sequence_ids = model.generate(input_ids)
+>>> sequences = tokenizer.batch_decode(sequence_ids)
+>>> sequences
+[' park offers the park.']
+```
+
+## Performance
+
+If you'd like a faster training and inference performance, install [NVIDIA APEX](https://github.com/NVIDIA/apex#quick-start) for NVIDIA GPUs, or [ROCm APEX](https://github.com/ROCmSoftwarePlatform/apex) for AMD GPUs and then the model will automatically use `apex.normalization.FusedRMSNorm` instead of `T5LayerNorm`. The former uses an optimized fused kernel which is several times faster than the latter.
+
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with T5. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- A notebook for how to [finetune T5 for classification and multiple choice](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/t5_fine_tuning.ipynb).
+- A notebook for how to [finetune T5 for sentiment span extraction](https://colab.research.google.com/github/enzoampil/t5-intro/blob/master/t5_qa_training_pytorch_span_extraction.ipynb). 🌎
+
+
+
+- A notebook for how to [finetune T5 for named entity recognition](https://colab.research.google.com/drive/1obr78FY_cBmWY5ODViCmzdY6O1KB65Vc?usp=sharing). 🌎
+
+
+
+- A notebook for [Finetuning CodeT5 for generating docstrings from Ruby code](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/T5/Fine_tune_CodeT5_for_generating_docstrings_from_Ruby_code.ipynb).
+
+
+
+- A notebook to [Finetune T5-base-dutch to perform Dutch abstractive summarization on a TPU](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/T5/Fine_tuning_Dutch_T5_base_on_CNN_Daily_Mail_for_summarization_(on_TPU_using_HuggingFace_Accelerate).ipynb).
+- A notebook for how to [finetune T5 for summarization in PyTorch and track experiments with WandB](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_summarization_wandb.ipynb#scrollTo=OKRpFvYhBauC). 🌎
+- A blog post on [Distributed Training: Train BART/T5 for Summarization using 🤗 Transformers and Amazon SageMaker](https://huggingface.co/blog/sagemaker-distributed-training-seq2seq).
+- [`T5ForConditionalGeneration`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization.ipynb).
+- [`TFT5ForConditionalGeneration`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/summarization) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization-tf.ipynb).
+- [`FlaxT5ForConditionalGeneration`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/flax/summarization).
+- [Summarization](https://huggingface.co/course/chapter7/5?fw=pt#summarization) chapter of the 🤗 Hugging Face course.
+- [Summarization task guide](../tasks/summarization)
+
+
+
+- [`FlaxT5ForConditionalGeneration`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/flax/language-modeling#t5-like-span-masked-language-modeling) for training T5 with a span-masked language model objective. The script also shows how to train a T5 tokenizer. [`FlaxT5ForConditionalGeneration`] is also supported by this [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/masked_language_modeling_flax.ipynb).
+
+
+
+- [`T5ForConditionalGeneration`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/translation) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation.ipynb).
+- [`TFT5ForConditionalGeneration`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/translation) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation-tf.ipynb).
+- [Translation task guide](../tasks/translation)
+
+
+
+- A notebook on how to [finetune T5 for question answering with TensorFlow 2](https://colab.research.google.com/github/snapthat/TF-T5-text-to-text/blob/master/snapthatT5/notebooks/TF-T5-Datasets%20Training.ipynb). 🌎
+- A notebook on how to [finetune T5 for question answering on a TPU](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb#scrollTo=QLGiFCDqvuil).
+
+🚀 **Deploy**
+- A blog post on how to deploy [T5 11B for inference for less than $500](https://www.philschmid.de/deploy-t5-11b).
+
+## T5Config
+
+[[autodoc]] T5Config
+
+## T5Tokenizer
+
+[[autodoc]] T5Tokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## T5TokenizerFast
+
+[[autodoc]] T5TokenizerFast
+
+
+
+
+## T5Model
+
+[[autodoc]] T5Model
+ - forward
+
+## T5ForConditionalGeneration
+
+[[autodoc]] T5ForConditionalGeneration
+ - forward
+
+## T5EncoderModel
+
+[[autodoc]] T5EncoderModel
+ - forward
+
+## T5ForSequenceClassification
+
+[[autodoc]] T5ForSequenceClassification
+ - forward
+
+## T5ForTokenClassification
+
+[[autodoc]] T5ForTokenClassification
+ - forward
+
+## T5ForQuestionAnswering
+
+[[autodoc]] T5ForQuestionAnswering
+ - forward
+
+
+
+
+## TFT5Model
+
+[[autodoc]] TFT5Model
+ - call
+
+## TFT5ForConditionalGeneration
+
+[[autodoc]] TFT5ForConditionalGeneration
+ - call
+
+## TFT5EncoderModel
+
+[[autodoc]] TFT5EncoderModel
+ - call
+
+
+
+
+## FlaxT5Model
+
+[[autodoc]] FlaxT5Model
+ - __call__
+ - encode
+ - decode
+
+## FlaxT5ForConditionalGeneration
+
+[[autodoc]] FlaxT5ForConditionalGeneration
+ - __call__
+ - encode
+ - decode
+
+## FlaxT5EncoderModel
+
+[[autodoc]] FlaxT5EncoderModel
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/t5v1.1.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/t5v1.1.md
new file mode 100644
index 0000000000000000000000000000000000000000..e18696f629df51c93af94f16d4365305e65d9875
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/t5v1.1.md
@@ -0,0 +1,71 @@
+
+
+# T5v1.1
+
+## Overview
+
+T5v1.1 was released in the [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511)
+repository by Colin Raffel et al. It's an improved version of the original T5 model.
+This model was contributed by [patrickvonplaten](https://huggingface.co/patrickvonplaten). The original code can be
+found [here](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511).
+
+## Usage tips
+
+One can directly plug in the weights of T5v1.1 into a T5 model, like so:
+
+```python
+>>> from transformers import T5ForConditionalGeneration
+
+>>> model = T5ForConditionalGeneration.from_pretrained("google/t5-v1_1-base")
+```
+
+T5 Version 1.1 includes the following improvements compared to the original T5 model:
+
+- GEGLU activation in the feed-forward hidden layer, rather than ReLU. See [this paper](https://arxiv.org/abs/2002.05202).
+
+- Dropout was turned off in pre-training (quality win). Dropout should be re-enabled during fine-tuning.
+
+- Pre-trained on C4 only without mixing in the downstream tasks.
+
+- No parameter sharing between the embedding and classifier layer.
+
+- "xl" and "xxl" replace "3B" and "11B". The model shapes are a bit different - larger `d_model` and smaller
+ `num_heads` and `d_ff`.
+
+Note: T5 Version 1.1 was only pre-trained on [C4](https://huggingface.co/datasets/c4) excluding any supervised
+training. Therefore, this model has to be fine-tuned before it is usable on a downstream task, unlike the original T5
+model. Since t5v1.1 was pre-trained unsupervisedly, there's no real advantage to using a task prefix during single-task
+fine-tuning. If you are doing multi-task fine-tuning, you should use a prefix.
+
+Google has released the following variants:
+
+- [google/t5-v1_1-small](https://huggingface.co/google/t5-v1_1-small)
+
+- [google/t5-v1_1-base](https://huggingface.co/google/t5-v1_1-base)
+
+- [google/t5-v1_1-large](https://huggingface.co/google/t5-v1_1-large)
+
+- [google/t5-v1_1-xl](https://huggingface.co/google/t5-v1_1-xl)
+
+- [google/t5-v1_1-xxl](https://huggingface.co/google/t5-v1_1-xxl).
+
+
+
+
+Refer to [T5's documentation page](t5) for all API reference, tips, code examples and notebooks.
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/table-transformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/table-transformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..850e7f50aa610f9548c395ab37eaa2d9e681dd99
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/table-transformer.md
@@ -0,0 +1,67 @@
+
+
+# Table Transformer
+
+## Overview
+
+The Table Transformer model was proposed in [PubTables-1M: Towards comprehensive table extraction from unstructured documents](https://arxiv.org/abs/2110.00061) by
+Brandon Smock, Rohith Pesala, Robin Abraham. The authors introduce a new dataset, PubTables-1M, to benchmark progress in table extraction from unstructured documents,
+as well as table structure recognition and functional analysis. The authors train 2 [DETR](detr) models, one for table detection and one for table structure recognition, dubbed Table Transformers.
+
+The abstract from the paper is the following:
+
+*Recently, significant progress has been made applying machine learning to the problem of table structure inference and extraction from unstructured documents.
+However, one of the greatest challenges remains the creation of datasets with complete, unambiguous ground truth at scale. To address this, we develop a new, more
+comprehensive dataset for table extraction, called PubTables-1M. PubTables-1M contains nearly one million tables from scientific articles, supports multiple input
+modalities, and contains detailed header and location information for table structures, making it useful for a wide variety of modeling approaches. It also addresses a significant
+source of ground truth inconsistency observed in prior datasets called oversegmentation, using a novel canonicalization procedure. We demonstrate that these improvements lead to a
+significant increase in training performance and a more reliable estimate of model performance at evaluation for table structure recognition. Further, we show that transformer-based
+object detection models trained on PubTables-1M produce excellent results for all three tasks of detection, structure recognition, and functional analysis without the need for any
+special customization for these tasks.*
+
+
+
+ Table detection and table structure recognition clarified. Taken from the original paper.
+
+The authors released 2 models, one for [table detection](https://huggingface.co/microsoft/table-transformer-detection) in
+documents, one for [table structure recognition](https://huggingface.co/microsoft/table-transformer-structure-recognition)
+(the task of recognizing the individual rows, columns etc. in a table).
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be
+found [here](https://github.com/microsoft/table-transformer).
+
+## Resources
+
+
+
+- A demo notebook for the Table Transformer can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Table%20Transformer).
+- It turns out padding of images is quite important for detection. An interesting Github thread with replies from the authors can be found [here](https://github.com/microsoft/table-transformer/issues/68).
+
+## TableTransformerConfig
+
+[[autodoc]] TableTransformerConfig
+
+## TableTransformerModel
+
+[[autodoc]] TableTransformerModel
+ - forward
+
+## TableTransformerForObjectDetection
+
+[[autodoc]] TableTransformerForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/tapas.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/tapas.md
new file mode 100644
index 0000000000000000000000000000000000000000..79bbe3e819cf864728baea5a5d556a42ca740202
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/tapas.md
@@ -0,0 +1,634 @@
+
+
+# TAPAS
+
+## Overview
+
+The TAPAS model was proposed in [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://www.aclweb.org/anthology/2020.acl-main.398)
+by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos. It's a BERT-based model specifically
+designed (and pre-trained) for answering questions about tabular data. Compared to BERT, TAPAS uses relative position embeddings and has 7
+token types that encode tabular structure. TAPAS is pre-trained on the masked language modeling (MLM) objective on a large dataset comprising
+millions of tables from English Wikipedia and corresponding texts.
+
+For question answering, TAPAS has 2 heads on top: a cell selection head and an aggregation head, for (optionally) performing aggregations (such as counting or summing) among selected cells. TAPAS has been fine-tuned on several datasets:
+- [SQA](https://www.microsoft.com/en-us/download/details.aspx?id=54253) (Sequential Question Answering by Microsoft)
+- [WTQ](https://github.com/ppasupat/WikiTableQuestions) (Wiki Table Questions by Stanford University)
+- [WikiSQL](https://github.com/salesforce/WikiSQL) (by Salesforce).
+
+It achieves state-of-the-art on both SQA and WTQ, while having comparable performance to SOTA on WikiSQL, with a much simpler architecture.
+
+The abstract from the paper is the following:
+
+*Answering natural language questions over tables is usually seen as a semantic parsing task. To alleviate the collection cost of full logical forms, one popular approach focuses on weak supervision consisting of denotations instead of logical forms. However, training semantic parsers from weak supervision poses difficulties, and in addition, the generated logical forms are only used as an intermediate step prior to retrieving the denotation. In this paper, we present TAPAS, an approach to question answering over tables without generating logical forms. TAPAS trains from weak supervision, and predicts the denotation by selecting table cells and optionally applying a corresponding aggregation operator to such selection. TAPAS extends BERT's architecture to encode tables as input, initializes from an effective joint pre-training of text segments and tables crawled from Wikipedia, and is trained end-to-end. We experiment with three different semantic parsing datasets, and find that TAPAS outperforms or rivals semantic parsing models by improving state-of-the-art accuracy on SQA from 55.1 to 67.2 and performing on par with the state-of-the-art on WIKISQL and WIKITQ, but with a simpler model architecture. We additionally find that transfer learning, which is trivial in our setting, from WIKISQL to WIKITQ, yields 48.7 accuracy, 4.2 points above the state-of-the-art.*
+
+In addition, the authors have further pre-trained TAPAS to recognize **table entailment**, by creating a balanced dataset of millions of automatically created training examples which are learned in an intermediate step prior to fine-tuning. The authors of TAPAS call this further pre-training intermediate pre-training (since TAPAS is first pre-trained on MLM, and then on another dataset). They found that intermediate pre-training further improves performance on SQA, achieving a new state-of-the-art as well as state-of-the-art on [TabFact](https://github.com/wenhuchen/Table-Fact-Checking), a large-scale dataset with 16k Wikipedia tables for table entailment (a binary classification task). For more details, see their follow-up paper: [Understanding tables with intermediate pre-training](https://www.aclweb.org/anthology/2020.findings-emnlp.27/) by Julian Martin Eisenschlos, Syrine Krichene and Thomas Müller.
+
+
+
+ TAPAS architecture. Taken from the original blog post.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The Tensorflow version of this model was contributed by [kamalkraj](https://huggingface.co/kamalkraj). The original code can be found [here](https://github.com/google-research/tapas).
+
+## Usage tips
+
+- TAPAS is a model that uses relative position embeddings by default (restarting the position embeddings at every cell of the table). Note that this is something that was added after the publication of the original TAPAS paper. According to the authors, this usually results in a slightly better performance, and allows you to encode longer sequences without running out of embeddings. This is reflected in the `reset_position_index_per_cell` parameter of [`TapasConfig`], which is set to `True` by default. The default versions of the models available on the [hub](https://huggingface.co/models?search=tapas) all use relative position embeddings. You can still use the ones with absolute position embeddings by passing in an additional argument `revision="no_reset"` when calling the `from_pretrained()` method. Note that it's usually advised to pad the inputs on the right rather than the left.
+- TAPAS is based on BERT, so `TAPAS-base` for example corresponds to a `BERT-base` architecture. Of course, `TAPAS-large` will result in the best performance (the results reported in the paper are from `TAPAS-large`). Results of the various sized models are shown on the [original GitHub repository](https://github.com/google-research/tapas).
+- TAPAS has checkpoints fine-tuned on SQA, which are capable of answering questions related to a table in a conversational set-up. This means that you can ask follow-up questions such as "what is his age?" related to the previous question. Note that the forward pass of TAPAS is a bit different in case of a conversational set-up: in that case, you have to feed every table-question pair one by one to the model, such that the `prev_labels` token type ids can be overwritten by the predicted `labels` of the model to the previous question. See "Usage" section for more info.
+- TAPAS is similar to BERT and therefore relies on the masked language modeling (MLM) objective. It is therefore efficient at predicting masked tokens and at NLU in general, but is not optimal for text generation. Models trained with a causal language modeling (CLM) objective are better in that regard. Note that TAPAS can be used as an encoder in the EncoderDecoderModel framework, to combine it with an autoregressive text decoder such as GPT-2.
+
+## Usage: fine-tuning
+
+Here we explain how you can fine-tune [`TapasForQuestionAnswering`] on your own dataset.
+
+**STEP 1: Choose one of the 3 ways in which you can use TAPAS - or experiment**
+
+Basically, there are 3 different ways in which one can fine-tune [`TapasForQuestionAnswering`], corresponding to the different datasets on which Tapas was fine-tuned:
+
+1. SQA: if you're interested in asking follow-up questions related to a table, in a conversational set-up. For example if you first ask "what's the name of the first actor?" then you can ask a follow-up question such as "how old is he?". Here, questions do not involve any aggregation (all questions are cell selection questions).
+2. WTQ: if you're not interested in asking questions in a conversational set-up, but rather just asking questions related to a table, which might involve aggregation, such as counting a number of rows, summing up cell values or averaging cell values. You can then for example ask "what's the total number of goals Cristiano Ronaldo made in his career?". This case is also called **weak supervision**, since the model itself must learn the appropriate aggregation operator (SUM/COUNT/AVERAGE/NONE) given only the answer to the question as supervision.
+3. WikiSQL-supervised: this dataset is based on WikiSQL with the model being given the ground truth aggregation operator during training. This is also called **strong supervision**. Here, learning the appropriate aggregation operator is much easier.
+
+To summarize:
+
+| **Task** | **Example dataset** | **Description** |
+|-------------------------------------|---------------------|---------------------------------------------------------------------------------------------------------|
+| Conversational | SQA | Conversational, only cell selection questions |
+| Weak supervision for aggregation | WTQ | Questions might involve aggregation, and the model must learn this given only the answer as supervision |
+| Strong supervision for aggregation | WikiSQL-supervised | Questions might involve aggregation, and the model must learn this given the gold aggregation operator |
+
+
+
+Initializing a model with a pre-trained base and randomly initialized classification heads from the hub can be done as shown below.
+
+```py
+>>> from transformers import TapasConfig, TapasForQuestionAnswering
+
+>>> # for example, the base sized model with default SQA configuration
+>>> model = TapasForQuestionAnswering.from_pretrained("google/tapas-base")
+
+>>> # or, the base sized model with WTQ configuration
+>>> config = TapasConfig.from_pretrained("google/tapas-base-finetuned-wtq")
+>>> model = TapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+
+>>> # or, the base sized model with WikiSQL configuration
+>>> config = TapasConfig("google-base-finetuned-wikisql-supervised")
+>>> model = TapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+```
+
+Of course, you don't necessarily have to follow one of these three ways in which TAPAS was fine-tuned. You can also experiment by defining any hyperparameters you want when initializing [`TapasConfig`], and then create a [`TapasForQuestionAnswering`] based on that configuration. For example, if you have a dataset that has both conversational questions and questions that might involve aggregation, then you can do it this way. Here's an example:
+
+```py
+>>> from transformers import TapasConfig, TapasForQuestionAnswering
+
+>>> # you can initialize the classification heads any way you want (see docs of TapasConfig)
+>>> config = TapasConfig(num_aggregation_labels=3, average_logits_per_cell=True)
+>>> # initializing the pre-trained base sized model with our custom classification heads
+>>> model = TapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+```
+
+
+Initializing a model with a pre-trained base and randomly initialized classification heads from the hub can be done as shown below. Be sure to have installed the [tensorflow_probability](https://github.com/tensorflow/probability) dependency:
+
+```py
+>>> from transformers import TapasConfig, TFTapasForQuestionAnswering
+
+>>> # for example, the base sized model with default SQA configuration
+>>> model = TFTapasForQuestionAnswering.from_pretrained("google/tapas-base")
+
+>>> # or, the base sized model with WTQ configuration
+>>> config = TapasConfig.from_pretrained("google/tapas-base-finetuned-wtq")
+>>> model = TFTapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+
+>>> # or, the base sized model with WikiSQL configuration
+>>> config = TapasConfig("google-base-finetuned-wikisql-supervised")
+>>> model = TFTapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+```
+
+Of course, you don't necessarily have to follow one of these three ways in which TAPAS was fine-tuned. You can also experiment by defining any hyperparameters you want when initializing [`TapasConfig`], and then create a [`TFTapasForQuestionAnswering`] based on that configuration. For example, if you have a dataset that has both conversational questions and questions that might involve aggregation, then you can do it this way. Here's an example:
+
+```py
+>>> from transformers import TapasConfig, TFTapasForQuestionAnswering
+
+>>> # you can initialize the classification heads any way you want (see docs of TapasConfig)
+>>> config = TapasConfig(num_aggregation_labels=3, average_logits_per_cell=True)
+>>> # initializing the pre-trained base sized model with our custom classification heads
+>>> model = TFTapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+```
+
+
+
+What you can also do is start from an already fine-tuned checkpoint. A note here is that the already fine-tuned checkpoint on WTQ has some issues due to the L2-loss which is somewhat brittle. See [here](https://github.com/google-research/tapas/issues/91#issuecomment-735719340) for more info.
+
+For a list of all pre-trained and fine-tuned TAPAS checkpoints available on HuggingFace's hub, see [here](https://huggingface.co/models?search=tapas).
+
+**STEP 2: Prepare your data in the SQA format**
+
+Second, no matter what you picked above, you should prepare your dataset in the [SQA](https://www.microsoft.com/en-us/download/details.aspx?id=54253) format. This format is a TSV/CSV file with the following columns:
+
+- `id`: optional, id of the table-question pair, for bookkeeping purposes.
+- `annotator`: optional, id of the person who annotated the table-question pair, for bookkeeping purposes.
+- `position`: integer indicating if the question is the first, second, third,... related to the table. Only required in case of conversational setup (SQA). You don't need this column in case you're going for WTQ/WikiSQL-supervised.
+- `question`: string
+- `table_file`: string, name of a csv file containing the tabular data
+- `answer_coordinates`: list of one or more tuples (each tuple being a cell coordinate, i.e. row, column pair that is part of the answer)
+- `answer_text`: list of one or more strings (each string being a cell value that is part of the answer)
+- `aggregation_label`: index of the aggregation operator. Only required in case of strong supervision for aggregation (the WikiSQL-supervised case)
+- `float_answer`: the float answer to the question, if there is one (np.nan if there isn't). Only required in case of weak supervision for aggregation (such as WTQ and WikiSQL)
+
+The tables themselves should be present in a folder, each table being a separate csv file. Note that the authors of the TAPAS algorithm used conversion scripts with some automated logic to convert the other datasets (WTQ, WikiSQL) into the SQA format. The author explains this [here](https://github.com/google-research/tapas/issues/50#issuecomment-705465960). A conversion of this script that works with HuggingFace's implementation can be found [here](https://github.com/NielsRogge/tapas_utils). Interestingly, these conversion scripts are not perfect (the `answer_coordinates` and `float_answer` fields are populated based on the `answer_text`), meaning that WTQ and WikiSQL results could actually be improved.
+
+**STEP 3: Convert your data into tensors using TapasTokenizer**
+
+
+
+Third, given that you've prepared your data in this TSV/CSV format (and corresponding CSV files containing the tabular data), you can then use [`TapasTokenizer`] to convert table-question pairs into `input_ids`, `attention_mask`, `token_type_ids` and so on. Again, based on which of the three cases you picked above, [`TapasForQuestionAnswering`] requires different
+inputs to be fine-tuned:
+
+| **Task** | **Required inputs** |
+|------------------------------------|---------------------------------------------------------------------------------------------------------------------|
+| Conversational | `input_ids`, `attention_mask`, `token_type_ids`, `labels` |
+| Weak supervision for aggregation | `input_ids`, `attention_mask`, `token_type_ids`, `labels`, `numeric_values`, `numeric_values_scale`, `float_answer` |
+| Strong supervision for aggregation | `input ids`, `attention mask`, `token type ids`, `labels`, `aggregation_labels` |
+
+[`TapasTokenizer`] creates the `labels`, `numeric_values` and `numeric_values_scale` based on the `answer_coordinates` and `answer_text` columns of the TSV file. The `float_answer` and `aggregation_labels` are already in the TSV file of step 2. Here's an example:
+
+```py
+>>> from transformers import TapasTokenizer
+>>> import pandas as pd
+
+>>> model_name = "google/tapas-base"
+>>> tokenizer = TapasTokenizer.from_pretrained(model_name)
+
+>>> data = {"Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"], "Number of movies": ["87", "53", "69"]}
+>>> queries = [
+... "What is the name of the first actor?",
+... "How many movies has George Clooney played in?",
+... "What is the total number of movies?",
+... ]
+>>> answer_coordinates = [[(0, 0)], [(2, 1)], [(0, 1), (1, 1), (2, 1)]]
+>>> answer_text = [["Brad Pitt"], ["69"], ["209"]]
+>>> table = pd.DataFrame.from_dict(data)
+>>> inputs = tokenizer(
+... table=table,
+... queries=queries,
+... answer_coordinates=answer_coordinates,
+... answer_text=answer_text,
+... padding="max_length",
+... return_tensors="pt",
+... )
+>>> inputs
+{'input_ids': tensor([[ ... ]]), 'attention_mask': tensor([[...]]), 'token_type_ids': tensor([[[...]]]),
+'numeric_values': tensor([[ ... ]]), 'numeric_values_scale: tensor([[ ... ]]), labels: tensor([[ ... ]])}
+```
+
+Note that [`TapasTokenizer`] expects the data of the table to be **text-only**. You can use `.astype(str)` on a dataframe to turn it into text-only data.
+Of course, this only shows how to encode a single training example. It is advised to create a dataloader to iterate over batches:
+
+```py
+>>> import torch
+>>> import pandas as pd
+
+>>> tsv_path = "your_path_to_the_tsv_file"
+>>> table_csv_path = "your_path_to_a_directory_containing_all_csv_files"
+
+
+>>> class TableDataset(torch.utils.data.Dataset):
+... def __init__(self, data, tokenizer):
+... self.data = data
+... self.tokenizer = tokenizer
+
+... def __getitem__(self, idx):
+... item = data.iloc[idx]
+... table = pd.read_csv(table_csv_path + item.table_file).astype(
+... str
+... ) # be sure to make your table data text only
+... encoding = self.tokenizer(
+... table=table,
+... queries=item.question,
+... answer_coordinates=item.answer_coordinates,
+... answer_text=item.answer_text,
+... truncation=True,
+... padding="max_length",
+... return_tensors="pt",
+... )
+... # remove the batch dimension which the tokenizer adds by default
+... encoding = {key: val.squeeze(0) for key, val in encoding.items()}
+... # add the float_answer which is also required (weak supervision for aggregation case)
+... encoding["float_answer"] = torch.tensor(item.float_answer)
+... return encoding
+
+... def __len__(self):
+... return len(self.data)
+
+
+>>> data = pd.read_csv(tsv_path, sep="\t")
+>>> train_dataset = TableDataset(data, tokenizer)
+>>> train_dataloader = torch.utils.data.DataLoader(train_dataset, batch_size=32)
+```
+
+
+Third, given that you've prepared your data in this TSV/CSV format (and corresponding CSV files containing the tabular data), you can then use [`TapasTokenizer`] to convert table-question pairs into `input_ids`, `attention_mask`, `token_type_ids` and so on. Again, based on which of the three cases you picked above, [`TFTapasForQuestionAnswering`] requires different
+inputs to be fine-tuned:
+
+| **Task** | **Required inputs** |
+|------------------------------------|---------------------------------------------------------------------------------------------------------------------|
+| Conversational | `input_ids`, `attention_mask`, `token_type_ids`, `labels` |
+| Weak supervision for aggregation | `input_ids`, `attention_mask`, `token_type_ids`, `labels`, `numeric_values`, `numeric_values_scale`, `float_answer` |
+| Strong supervision for aggregation | `input ids`, `attention mask`, `token type ids`, `labels`, `aggregation_labels` |
+
+[`TapasTokenizer`] creates the `labels`, `numeric_values` and `numeric_values_scale` based on the `answer_coordinates` and `answer_text` columns of the TSV file. The `float_answer` and `aggregation_labels` are already in the TSV file of step 2. Here's an example:
+
+```py
+>>> from transformers import TapasTokenizer
+>>> import pandas as pd
+
+>>> model_name = "google/tapas-base"
+>>> tokenizer = TapasTokenizer.from_pretrained(model_name)
+
+>>> data = {"Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"], "Number of movies": ["87", "53", "69"]}
+>>> queries = [
+... "What is the name of the first actor?",
+... "How many movies has George Clooney played in?",
+... "What is the total number of movies?",
+... ]
+>>> answer_coordinates = [[(0, 0)], [(2, 1)], [(0, 1), (1, 1), (2, 1)]]
+>>> answer_text = [["Brad Pitt"], ["69"], ["209"]]
+>>> table = pd.DataFrame.from_dict(data)
+>>> inputs = tokenizer(
+... table=table,
+... queries=queries,
+... answer_coordinates=answer_coordinates,
+... answer_text=answer_text,
+... padding="max_length",
+... return_tensors="tf",
+... )
+>>> inputs
+{'input_ids': tensor([[ ... ]]), 'attention_mask': tensor([[...]]), 'token_type_ids': tensor([[[...]]]),
+'numeric_values': tensor([[ ... ]]), 'numeric_values_scale: tensor([[ ... ]]), labels: tensor([[ ... ]])}
+```
+
+Note that [`TapasTokenizer`] expects the data of the table to be **text-only**. You can use `.astype(str)` on a dataframe to turn it into text-only data.
+Of course, this only shows how to encode a single training example. It is advised to create a dataloader to iterate over batches:
+
+```py
+>>> import tensorflow as tf
+>>> import pandas as pd
+
+>>> tsv_path = "your_path_to_the_tsv_file"
+>>> table_csv_path = "your_path_to_a_directory_containing_all_csv_files"
+
+
+>>> class TableDataset:
+... def __init__(self, data, tokenizer):
+... self.data = data
+... self.tokenizer = tokenizer
+
+... def __iter__(self):
+... for idx in range(self.__len__()):
+... item = self.data.iloc[idx]
+... table = pd.read_csv(table_csv_path + item.table_file).astype(
+... str
+... ) # be sure to make your table data text only
+... encoding = self.tokenizer(
+... table=table,
+... queries=item.question,
+... answer_coordinates=item.answer_coordinates,
+... answer_text=item.answer_text,
+... truncation=True,
+... padding="max_length",
+... return_tensors="tf",
+... )
+... # remove the batch dimension which the tokenizer adds by default
+... encoding = {key: tf.squeeze(val, 0) for key, val in encoding.items()}
+... # add the float_answer which is also required (weak supervision for aggregation case)
+... encoding["float_answer"] = tf.convert_to_tensor(item.float_answer, dtype=tf.float32)
+... yield encoding["input_ids"], encoding["attention_mask"], encoding["numeric_values"], encoding[
+... "numeric_values_scale"
+... ], encoding["token_type_ids"], encoding["labels"], encoding["float_answer"]
+
+... def __len__(self):
+... return len(self.data)
+
+
+>>> data = pd.read_csv(tsv_path, sep="\t")
+>>> train_dataset = TableDataset(data, tokenizer)
+>>> output_signature = (
+... tf.TensorSpec(shape=(512,), dtype=tf.int32),
+... tf.TensorSpec(shape=(512,), dtype=tf.int32),
+... tf.TensorSpec(shape=(512,), dtype=tf.float32),
+... tf.TensorSpec(shape=(512,), dtype=tf.float32),
+... tf.TensorSpec(shape=(512, 7), dtype=tf.int32),
+... tf.TensorSpec(shape=(512,), dtype=tf.int32),
+... tf.TensorSpec(shape=(512,), dtype=tf.float32),
+... )
+>>> train_dataloader = tf.data.Dataset.from_generator(train_dataset, output_signature=output_signature).batch(32)
+```
+
+
+
+Note that here, we encode each table-question pair independently. This is fine as long as your dataset is **not conversational**. In case your dataset involves conversational questions (such as in SQA), then you should first group together the `queries`, `answer_coordinates` and `answer_text` per table (in the order of their `position`
+index) and batch encode each table with its questions. This will make sure that the `prev_labels` token types (see docs of [`TapasTokenizer`]) are set correctly. See [this notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb) for more info. See [this notebook](https://github.com/kamalkraj/Tapas-Tutorial/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb) for more info regarding using the TensorFlow model.
+
+**STEP 4: Train (fine-tune) the model
+
+
+
+You can then fine-tune [`TapasForQuestionAnswering`] as follows (shown here for the weak supervision for aggregation case):
+
+```py
+>>> from transformers import TapasConfig, TapasForQuestionAnswering, AdamW
+
+>>> # this is the default WTQ configuration
+>>> config = TapasConfig(
+... num_aggregation_labels=4,
+... use_answer_as_supervision=True,
+... answer_loss_cutoff=0.664694,
+... cell_selection_preference=0.207951,
+... huber_loss_delta=0.121194,
+... init_cell_selection_weights_to_zero=True,
+... select_one_column=True,
+... allow_empty_column_selection=False,
+... temperature=0.0352513,
+... )
+>>> model = TapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+
+>>> optimizer = AdamW(model.parameters(), lr=5e-5)
+
+>>> model.train()
+>>> for epoch in range(2): # loop over the dataset multiple times
+... for batch in train_dataloader:
+... # get the inputs;
+... input_ids = batch["input_ids"]
+... attention_mask = batch["attention_mask"]
+... token_type_ids = batch["token_type_ids"]
+... labels = batch["labels"]
+... numeric_values = batch["numeric_values"]
+... numeric_values_scale = batch["numeric_values_scale"]
+... float_answer = batch["float_answer"]
+
+... # zero the parameter gradients
+... optimizer.zero_grad()
+
+... # forward + backward + optimize
+... outputs = model(
+... input_ids=input_ids,
+... attention_mask=attention_mask,
+... token_type_ids=token_type_ids,
+... labels=labels,
+... numeric_values=numeric_values,
+... numeric_values_scale=numeric_values_scale,
+... float_answer=float_answer,
+... )
+... loss = outputs.loss
+... loss.backward()
+... optimizer.step()
+```
+
+
+You can then fine-tune [`TFTapasForQuestionAnswering`] as follows (shown here for the weak supervision for aggregation case):
+
+```py
+>>> import tensorflow as tf
+>>> from transformers import TapasConfig, TFTapasForQuestionAnswering
+
+>>> # this is the default WTQ configuration
+>>> config = TapasConfig(
+... num_aggregation_labels=4,
+... use_answer_as_supervision=True,
+... answer_loss_cutoff=0.664694,
+... cell_selection_preference=0.207951,
+... huber_loss_delta=0.121194,
+... init_cell_selection_weights_to_zero=True,
+... select_one_column=True,
+... allow_empty_column_selection=False,
+... temperature=0.0352513,
+... )
+>>> model = TFTapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+
+>>> optimizer = tf.keras.optimizers.Adam(learning_rate=5e-5)
+
+>>> for epoch in range(2): # loop over the dataset multiple times
+... for batch in train_dataloader:
+... # get the inputs;
+... input_ids = batch[0]
+... attention_mask = batch[1]
+... token_type_ids = batch[4]
+... labels = batch[-1]
+... numeric_values = batch[2]
+... numeric_values_scale = batch[3]
+... float_answer = batch[6]
+
+... # forward + backward + optimize
+... with tf.GradientTape() as tape:
+... outputs = model(
+... input_ids=input_ids,
+... attention_mask=attention_mask,
+... token_type_ids=token_type_ids,
+... labels=labels,
+... numeric_values=numeric_values,
+... numeric_values_scale=numeric_values_scale,
+... float_answer=float_answer,
+... )
+... grads = tape.gradient(outputs.loss, model.trainable_weights)
+... optimizer.apply_gradients(zip(grads, model.trainable_weights))
+```
+
+
+
+## Usage: inference
+
+
+
+Here we explain how you can use [`TapasForQuestionAnswering`] or [`TFTapasForQuestionAnswering`] for inference (i.e. making predictions on new data). For inference, only `input_ids`, `attention_mask` and `token_type_ids` (which you can obtain using [`TapasTokenizer`]) have to be provided to the model to obtain the logits. Next, you can use the handy [`~models.tapas.tokenization_tapas.convert_logits_to_predictions`] method to convert these into predicted coordinates and optional aggregation indices.
+
+However, note that inference is **different** depending on whether or not the setup is conversational. In a non-conversational set-up, inference can be done in parallel on all table-question pairs of a batch. Here's an example of that:
+
+```py
+>>> from transformers import TapasTokenizer, TapasForQuestionAnswering
+>>> import pandas as pd
+
+>>> model_name = "google/tapas-base-finetuned-wtq"
+>>> model = TapasForQuestionAnswering.from_pretrained(model_name)
+>>> tokenizer = TapasTokenizer.from_pretrained(model_name)
+
+>>> data = {"Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"], "Number of movies": ["87", "53", "69"]}
+>>> queries = [
+... "What is the name of the first actor?",
+... "How many movies has George Clooney played in?",
+... "What is the total number of movies?",
+... ]
+>>> table = pd.DataFrame.from_dict(data)
+>>> inputs = tokenizer(table=table, queries=queries, padding="max_length", return_tensors="pt")
+>>> outputs = model(**inputs)
+>>> predicted_answer_coordinates, predicted_aggregation_indices = tokenizer.convert_logits_to_predictions(
+... inputs, outputs.logits.detach(), outputs.logits_aggregation.detach()
+... )
+
+>>> # let's print out the results:
+>>> id2aggregation = {0: "NONE", 1: "SUM", 2: "AVERAGE", 3: "COUNT"}
+>>> aggregation_predictions_string = [id2aggregation[x] for x in predicted_aggregation_indices]
+
+>>> answers = []
+>>> for coordinates in predicted_answer_coordinates:
+... if len(coordinates) == 1:
+... # only a single cell:
+... answers.append(table.iat[coordinates[0]])
+... else:
+... # multiple cells
+... cell_values = []
+... for coordinate in coordinates:
+... cell_values.append(table.iat[coordinate])
+... answers.append(", ".join(cell_values))
+
+>>> display(table)
+>>> print("")
+>>> for query, answer, predicted_agg in zip(queries, answers, aggregation_predictions_string):
+... print(query)
+... if predicted_agg == "NONE":
+... print("Predicted answer: " + answer)
+... else:
+... print("Predicted answer: " + predicted_agg + " > " + answer)
+What is the name of the first actor?
+Predicted answer: Brad Pitt
+How many movies has George Clooney played in?
+Predicted answer: COUNT > 69
+What is the total number of movies?
+Predicted answer: SUM > 87, 53, 69
+```
+
+
+Here we explain how you can use [`TFTapasForQuestionAnswering`] for inference (i.e. making predictions on new data). For inference, only `input_ids`, `attention_mask` and `token_type_ids` (which you can obtain using [`TapasTokenizer`]) have to be provided to the model to obtain the logits. Next, you can use the handy [`~models.tapas.tokenization_tapas.convert_logits_to_predictions`] method to convert these into predicted coordinates and optional aggregation indices.
+
+However, note that inference is **different** depending on whether or not the setup is conversational. In a non-conversational set-up, inference can be done in parallel on all table-question pairs of a batch. Here's an example of that:
+
+```py
+>>> from transformers import TapasTokenizer, TFTapasForQuestionAnswering
+>>> import pandas as pd
+
+>>> model_name = "google/tapas-base-finetuned-wtq"
+>>> model = TFTapasForQuestionAnswering.from_pretrained(model_name)
+>>> tokenizer = TapasTokenizer.from_pretrained(model_name)
+
+>>> data = {"Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"], "Number of movies": ["87", "53", "69"]}
+>>> queries = [
+... "What is the name of the first actor?",
+... "How many movies has George Clooney played in?",
+... "What is the total number of movies?",
+... ]
+>>> table = pd.DataFrame.from_dict(data)
+>>> inputs = tokenizer(table=table, queries=queries, padding="max_length", return_tensors="tf")
+>>> outputs = model(**inputs)
+>>> predicted_answer_coordinates, predicted_aggregation_indices = tokenizer.convert_logits_to_predictions(
+... inputs, outputs.logits, outputs.logits_aggregation
+... )
+
+>>> # let's print out the results:
+>>> id2aggregation = {0: "NONE", 1: "SUM", 2: "AVERAGE", 3: "COUNT"}
+>>> aggregation_predictions_string = [id2aggregation[x] for x in predicted_aggregation_indices]
+
+>>> answers = []
+>>> for coordinates in predicted_answer_coordinates:
+... if len(coordinates) == 1:
+... # only a single cell:
+... answers.append(table.iat[coordinates[0]])
+... else:
+... # multiple cells
+... cell_values = []
+... for coordinate in coordinates:
+... cell_values.append(table.iat[coordinate])
+... answers.append(", ".join(cell_values))
+
+>>> display(table)
+>>> print("")
+>>> for query, answer, predicted_agg in zip(queries, answers, aggregation_predictions_string):
+... print(query)
+... if predicted_agg == "NONE":
+... print("Predicted answer: " + answer)
+... else:
+... print("Predicted answer: " + predicted_agg + " > " + answer)
+What is the name of the first actor?
+Predicted answer: Brad Pitt
+How many movies has George Clooney played in?
+Predicted answer: COUNT > 69
+What is the total number of movies?
+Predicted answer: SUM > 87, 53, 69
+```
+
+
+
+In case of a conversational set-up, then each table-question pair must be provided **sequentially** to the model, such that the `prev_labels` token types can be overwritten by the predicted `labels` of the previous table-question pair. Again, more info can be found in [this notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb) (for PyTorch) and [this notebook](https://github.com/kamalkraj/Tapas-Tutorial/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb) (for TensorFlow).
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+
+## TAPAS specific outputs
+[[autodoc]] models.tapas.modeling_tapas.TableQuestionAnsweringOutput
+
+## TapasConfig
+[[autodoc]] TapasConfig
+
+## TapasTokenizer
+[[autodoc]] TapasTokenizer
+ - __call__
+ - convert_logits_to_predictions
+ - save_vocabulary
+
+
+
+
+## TapasModel
+[[autodoc]] TapasModel
+ - forward
+
+## TapasForMaskedLM
+[[autodoc]] TapasForMaskedLM
+ - forward
+
+## TapasForSequenceClassification
+[[autodoc]] TapasForSequenceClassification
+ - forward
+
+## TapasForQuestionAnswering
+[[autodoc]] TapasForQuestionAnswering
+ - forward
+
+
+
+
+## TFTapasModel
+[[autodoc]] TFTapasModel
+ - call
+
+## TFTapasForMaskedLM
+[[autodoc]] TFTapasForMaskedLM
+ - call
+
+## TFTapasForSequenceClassification
+[[autodoc]] TFTapasForSequenceClassification
+ - call
+
+## TFTapasForQuestionAnswering
+[[autodoc]] TFTapasForQuestionAnswering
+ - call
+
+
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/tapex.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/tapex.md
new file mode 100644
index 0000000000000000000000000000000000000000..15ac2463fd851dca72d82c43ab05a1253e202dce
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/tapex.md
@@ -0,0 +1,149 @@
+
+
+# TAPEX
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.30.0.
+You can do so by running the following command: `pip install -U transformers==4.30.0`.
+
+
+
+## Overview
+
+The TAPEX model was proposed in [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://arxiv.org/abs/2107.07653) by Qian Liu,
+Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou. TAPEX pre-trains a BART model to solve synthetic SQL queries, after
+which it can be fine-tuned to answer natural language questions related to tabular data, as well as performing table fact checking.
+
+TAPEX has been fine-tuned on several datasets:
+- [SQA](https://www.microsoft.com/en-us/download/details.aspx?id=54253) (Sequential Question Answering by Microsoft)
+- [WTQ](https://github.com/ppasupat/WikiTableQuestions) (Wiki Table Questions by Stanford University)
+- [WikiSQL](https://github.com/salesforce/WikiSQL) (by Salesforce)
+- [TabFact](https://tabfact.github.io/) (by USCB NLP Lab).
+
+The abstract from the paper is the following:
+
+*Recent progress in language model pre-training has achieved a great success via leveraging large-scale unstructured textual data. However, it is
+still a challenge to apply pre-training on structured tabular data due to the absence of large-scale high-quality tabular data. In this paper, we
+propose TAPEX to show that table pre-training can be achieved by learning a neural SQL executor over a synthetic corpus, which is obtained by automatically
+synthesizing executable SQL queries and their execution outputs. TAPEX addresses the data scarcity challenge via guiding the language model to mimic a SQL
+executor on the diverse, large-scale and high-quality synthetic corpus. We evaluate TAPEX on four benchmark datasets. Experimental results demonstrate that
+TAPEX outperforms previous table pre-training approaches by a large margin and achieves new state-of-the-art results on all of them. This includes improvements
+on the weakly-supervised WikiSQL denotation accuracy to 89.5% (+2.3%), the WikiTableQuestions denotation accuracy to 57.5% (+4.8%), the SQA denotation accuracy
+to 74.5% (+3.5%), and the TabFact accuracy to 84.2% (+3.2%). To our knowledge, this is the first work to exploit table pre-training via synthetic executable programs
+and to achieve new state-of-the-art results on various downstream tasks.*
+
+## Usage tips
+
+- TAPEX is a generative (seq2seq) model. One can directly plug in the weights of TAPEX into a BART model.
+- TAPEX has checkpoints on the hub that are either pre-trained only, or fine-tuned on WTQ, SQA, WikiSQL and TabFact.
+- Sentences + tables are presented to the model as `sentence + " " + linearized table`. The linearized table has the following format:
+ `col: col1 | col2 | col 3 row 1 : val1 | val2 | val3 row 2 : ...`.
+- TAPEX has its own tokenizer, that allows to prepare all data for the model easily. One can pass Pandas DataFrames and strings to the tokenizer,
+ and it will automatically create the `input_ids` and `attention_mask` (as shown in the usage examples below).
+
+### Usage: inference
+
+Below, we illustrate how to use TAPEX for table question answering. As one can see, one can directly plug in the weights of TAPEX into a BART model.
+We use the [Auto API](auto), which will automatically instantiate the appropriate tokenizer ([`TapexTokenizer`]) and model ([`BartForConditionalGeneration`]) for us,
+based on the configuration file of the checkpoint on the hub.
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+>>> import pandas as pd
+
+>>> tokenizer = AutoTokenizer.from_pretrained("microsoft/tapex-large-finetuned-wtq")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("microsoft/tapex-large-finetuned-wtq")
+
+>>> # prepare table + question
+>>> data = {"Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"], "Number of movies": ["87", "53", "69"]}
+>>> table = pd.DataFrame.from_dict(data)
+>>> question = "how many movies does Leonardo Di Caprio have?"
+
+>>> encoding = tokenizer(table, question, return_tensors="pt")
+
+>>> # let the model generate an answer autoregressively
+>>> outputs = model.generate(**encoding)
+
+>>> # decode back to text
+>>> predicted_answer = tokenizer.batch_decode(outputs, skip_special_tokens=True)[0]
+>>> print(predicted_answer)
+53
+```
+
+Note that [`TapexTokenizer`] also supports batched inference. Hence, one can provide a batch of different tables/questions, or a batch of a single table
+and multiple questions, or a batch of a single query and multiple tables. Let's illustrate this:
+
+```python
+>>> # prepare table + question
+>>> data = {"Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"], "Number of movies": ["87", "53", "69"]}
+>>> table = pd.DataFrame.from_dict(data)
+>>> questions = [
+... "how many movies does Leonardo Di Caprio have?",
+... "which actor has 69 movies?",
+... "what's the first name of the actor who has 87 movies?",
+... ]
+>>> encoding = tokenizer(table, questions, padding=True, return_tensors="pt")
+
+>>> # let the model generate an answer autoregressively
+>>> outputs = model.generate(**encoding)
+
+>>> # decode back to text
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+[' 53', ' george clooney', ' brad pitt']
+```
+
+In case one wants to do table verification (i.e. the task of determining whether a given sentence is supported or refuted by the contents
+of a table), one can instantiate a [`BartForSequenceClassification`] model. TAPEX has checkpoints on the hub fine-tuned on TabFact, an important
+benchmark for table fact checking (it achieves 84% accuracy). The code example below again leverages the [Auto API](auto).
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> tokenizer = AutoTokenizer.from_pretrained("microsoft/tapex-large-finetuned-tabfact")
+>>> model = AutoModelForSequenceClassification.from_pretrained("microsoft/tapex-large-finetuned-tabfact")
+
+>>> # prepare table + sentence
+>>> data = {"Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"], "Number of movies": ["87", "53", "69"]}
+>>> table = pd.DataFrame.from_dict(data)
+>>> sentence = "George Clooney has 30 movies"
+
+>>> encoding = tokenizer(table, sentence, return_tensors="pt")
+
+>>> # forward pass
+>>> outputs = model(**encoding)
+
+>>> # print prediction
+>>> predicted_class_idx = outputs.logits[0].argmax(dim=0).item()
+>>> print(model.config.id2label[predicted_class_idx])
+Refused
+```
+
+
+
+TAPEX architecture is the same as BART, except for tokenization. Refer to [BART documentation](bart) for information on
+configuration classes and their parameters. TAPEX-specific tokenizer is documented below.
+
+
+
+## TapexTokenizer
+
+[[autodoc]] TapexTokenizer
+ - __call__
+ - save_vocabulary
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/time_series_transformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/time_series_transformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..c5bfcfc15ea2a244d01bd5f94788a063200e394c
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/time_series_transformer.md
@@ -0,0 +1,72 @@
+
+
+# Time Series Transformer
+
+## Overview
+
+The Time Series Transformer model is a vanilla encoder-decoder Transformer for time series forecasting.
+This model was contributed by [kashif](https://huggingface.co/kashif).
+
+## Usage tips
+
+- Similar to other models in the library, [`TimeSeriesTransformerModel`] is the raw Transformer without any head on top, and [`TimeSeriesTransformerForPrediction`]
+adds a distribution head on top of the former, which can be used for time-series forecasting. Note that this is a so-called probabilistic forecasting model, not a
+point forecasting model. This means that the model learns a distribution, from which one can sample. The model doesn't directly output values.
+- [`TimeSeriesTransformerForPrediction`] consists of 2 blocks: an encoder, which takes a `context_length` of time series values as input (called `past_values`),
+and a decoder, which predicts a `prediction_length` of time series values into the future (called `future_values`). During training, one needs to provide
+pairs of (`past_values` and `future_values`) to the model.
+- In addition to the raw (`past_values` and `future_values`), one typically provides additional features to the model. These can be the following:
+ - `past_time_features`: temporal features which the model will add to `past_values`. These serve as "positional encodings" for the Transformer encoder.
+ Examples are "day of the month", "month of the year", etc. as scalar values (and then stacked together as a vector).
+ e.g. if a given time-series value was obtained on the 11th of August, then one could have [11, 8] as time feature vector (11 being "day of the month", 8 being "month of the year").
+ - `future_time_features`: temporal features which the model will add to `future_values`. These serve as "positional encodings" for the Transformer decoder.
+ Examples are "day of the month", "month of the year", etc. as scalar values (and then stacked together as a vector).
+ e.g. if a given time-series value was obtained on the 11th of August, then one could have [11, 8] as time feature vector (11 being "day of the month", 8 being "month of the year").
+ - `static_categorical_features`: categorical features which are static over time (i.e., have the same value for all `past_values` and `future_values`).
+ An example here is the store ID or region ID that identifies a given time-series.
+ Note that these features need to be known for ALL data points (also those in the future).
+ - `static_real_features`: real-valued features which are static over time (i.e., have the same value for all `past_values` and `future_values`).
+ An example here is the image representation of the product for which you have the time-series values (like the [ResNet](resnet) embedding of a "shoe" picture,
+ if your time-series is about the sales of shoes).
+ Note that these features need to be known for ALL data points (also those in the future).
+- The model is trained using "teacher-forcing", similar to how a Transformer is trained for machine translation. This means that, during training, one shifts the
+`future_values` one position to the right as input to the decoder, prepended by the last value of `past_values`. At each time step, the model needs to predict the
+next target. So the set-up of training is similar to a GPT model for language, except that there's no notion of `decoder_start_token_id` (we just use the last value
+of the context as initial input for the decoder).
+- At inference time, we give the final value of the `past_values` as input to the decoder. Next, we can sample from the model to make a prediction at the next time step,
+which is then fed to the decoder in order to make the next prediction (also called autoregressive generation).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- Check out the Time Series Transformer blog-post in HuggingFace blog: [Probabilistic Time Series Forecasting with 🤗 Transformers](https://huggingface.co/blog/time-series-transformers)
+
+
+## TimeSeriesTransformerConfig
+
+[[autodoc]] TimeSeriesTransformerConfig
+
+## TimeSeriesTransformerModel
+
+[[autodoc]] TimeSeriesTransformerModel
+ - forward
+
+## TimeSeriesTransformerForPrediction
+
+[[autodoc]] TimeSeriesTransformerForPrediction
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/timesformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/timesformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..fe75bee5b2897eb1dfb4bbb28fd7d5534083db9a
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/timesformer.md
@@ -0,0 +1,52 @@
+
+
+# TimeSformer
+
+## Overview
+
+The TimeSformer model was proposed in [TimeSformer: Is Space-Time Attention All You Need for Video Understanding?](https://arxiv.org/abs/2102.05095) by Facebook Research.
+This work is a milestone in action-recognition field being the first video transformer. It inspired many transformer based video understanding and classification papers.
+
+The abstract from the paper is the following:
+
+*We present a convolution-free approach to video classification built exclusively on self-attention over space and time. Our method, named "TimeSformer," adapts the standard Transformer architecture to video by enabling spatiotemporal feature learning directly from a sequence of frame-level patches. Our experimental study compares different self-attention schemes and suggests that "divided attention," where temporal attention and spatial attention are separately applied within each block, leads to the best video classification accuracy among the design choices considered. Despite the radically new design, TimeSformer achieves state-of-the-art results on several action recognition benchmarks, including the best reported accuracy on Kinetics-400 and Kinetics-600. Finally, compared to 3D convolutional networks, our model is faster to train, it can achieve dramatically higher test efficiency (at a small drop in accuracy), and it can also be applied to much longer video clips (over one minute long). Code and models are available at: [this https URL](https://github.com/facebookresearch/TimeSformer).*
+
+This model was contributed by [fcakyon](https://huggingface.co/fcakyon).
+The original code can be found [here](https://github.com/facebookresearch/TimeSformer).
+
+## Usage tips
+
+There are many pretrained variants. Select your pretrained model based on the dataset it is trained on. Moreover,
+the number of input frames per clip changes based on the model size so you should consider this parameter while selecting your pretrained model.
+
+## Resources
+
+- [Video classification task guide](../tasks/video_classification)
+
+## TimesformerConfig
+
+[[autodoc]] TimesformerConfig
+
+## TimesformerModel
+
+[[autodoc]] TimesformerModel
+ - forward
+
+## TimesformerForVideoClassification
+
+[[autodoc]] TimesformerForVideoClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/timm_wrapper.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/timm_wrapper.md
new file mode 100644
index 0000000000000000000000000000000000000000..5af3d51746c325cc9085076fdfc8feaaa1ddb350
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/timm_wrapper.md
@@ -0,0 +1,67 @@
+
+
+# TimmWrapper
+
+## Overview
+
+Helper class to enable loading timm models to be used with the transformers library and its autoclasses.
+
+```python
+>>> import torch
+>>> from PIL import Image
+>>> from urllib.request import urlopen
+>>> from transformers import AutoModelForImageClassification, AutoImageProcessor
+
+>>> # Load image
+>>> image = Image.open(urlopen(
+... 'https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/beignets-task-guide.png'
+... ))
+
+>>> # Load model and image processor
+>>> checkpoint = "timm/resnet50.a1_in1k"
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint)
+>>> model = AutoModelForImageClassification.from_pretrained(checkpoint).eval()
+
+>>> # Preprocess image
+>>> inputs = image_processor(image)
+
+>>> # Forward pass
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+
+>>> # Get top 5 predictions
+>>> top5_probabilities, top5_class_indices = torch.topk(logits.softmax(dim=1) * 100, k=5)
+```
+
+## TimmWrapperConfig
+
+[[autodoc]] TimmWrapperConfig
+
+## TimmWrapperImageProcessor
+
+[[autodoc]] TimmWrapperImageProcessor
+ - preprocess
+
+## TimmWrapperModel
+
+[[autodoc]] TimmWrapperModel
+ - forward
+
+## TimmWrapperForImageClassification
+
+[[autodoc]] TimmWrapperForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/trajectory_transformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/trajectory_transformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..45616255871a0807a023b31101af2685bd0685ae
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/trajectory_transformer.md
@@ -0,0 +1,61 @@
+
+
+# Trajectory Transformer
+
+
+
+This model is in maintenance mode only, so we won't accept any new PRs changing its code.
+
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.30.0.
+You can do so by running the following command: `pip install -U transformers==4.30.0`.
+
+
+
+## Overview
+
+The Trajectory Transformer model was proposed in [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://arxiv.org/abs/2106.02039) by Michael Janner, Qiyang Li, Sergey Levine.
+
+The abstract from the paper is the following:
+
+*Reinforcement learning (RL) is typically concerned with estimating stationary policies or single-step models,
+leveraging the Markov property to factorize problems in time. However, we can also view RL as a generic sequence
+modeling problem, with the goal being to produce a sequence of actions that leads to a sequence of high rewards.
+Viewed in this way, it is tempting to consider whether high-capacity sequence prediction models that work well
+in other domains, such as natural-language processing, can also provide effective solutions to the RL problem.
+To this end, we explore how RL can be tackled with the tools of sequence modeling, using a Transformer architecture
+to model distributions over trajectories and repurposing beam search as a planning algorithm. Framing RL as sequence
+modeling problem simplifies a range of design decisions, allowing us to dispense with many of the components common
+in offline RL algorithms. We demonstrate the flexibility of this approach across long-horizon dynamics prediction,
+imitation learning, goal-conditioned RL, and offline RL. Further, we show that this approach can be combined with
+existing model-free algorithms to yield a state-of-the-art planner in sparse-reward, long-horizon tasks.*
+
+This model was contributed by [CarlCochet](https://huggingface.co/CarlCochet). The original code can be found [here](https://github.com/jannerm/trajectory-transformer).
+
+## Usage tips
+
+This Transformer is used for deep reinforcement learning. To use it, you need to create sequences from
+actions, states and rewards from all previous timesteps. This model will treat all these elements together
+as one big sequence (a trajectory).
+
+## TrajectoryTransformerConfig
+
+[[autodoc]] TrajectoryTransformerConfig
+
+## TrajectoryTransformerModel
+
+[[autodoc]] TrajectoryTransformerModel
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/transfo-xl.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/transfo-xl.md
new file mode 100644
index 0000000000000000000000000000000000000000..c80d9352b5aef6376aad210a39ff6f2cc056d967
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/transfo-xl.md
@@ -0,0 +1,162 @@
+
+
+# Transformer XL
+
+
+
+This model is in maintenance mode only, so we won't accept any new PRs changing its code. This model was deprecated due to security issues linked to `pickle.load`.
+
+We recommend switching to more recent models for improved security.
+
+In case you would still like to use `TransfoXL` in your experiments, we recommend using the [Hub checkpoint](https://huggingface.co/transfo-xl/transfo-xl-wt103) with a specific revision to ensure you are downloading safe files from the Hub.
+
+You will need to set the environment variable `TRUST_REMOTE_CODE` to `True` in order to allow the
+usage of `pickle.load()`:
+
+```python
+import os
+from transformers import TransfoXLTokenizer, TransfoXLLMHeadModel
+
+os.environ["TRUST_REMOTE_CODE"] = "True"
+
+checkpoint = 'transfo-xl/transfo-xl-wt103'
+revision = '40a186da79458c9f9de846edfaea79c412137f97'
+
+tokenizer = TransfoXLTokenizer.from_pretrained(checkpoint, revision=revision)
+model = TransfoXLLMHeadModel.from_pretrained(checkpoint, revision=revision)
+```
+
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.35.0.
+You can do so by running the following command: `pip install -U transformers==4.35.0`.
+
+
+
+
+
+## Overview
+
+The Transformer-XL model was proposed in [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://arxiv.org/abs/1901.02860) by Zihang Dai, Zhilin Yang, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan
+Salakhutdinov. It's a causal (uni-directional) transformer with relative positioning (sinusoïdal) embeddings which can
+reuse previously computed hidden-states to attend to longer context (memory). This model also uses adaptive softmax
+inputs and outputs (tied).
+
+The abstract from the paper is the following:
+
+*Transformers have a potential of learning longer-term dependency, but are limited by a fixed-length context in the
+setting of language modeling. We propose a novel neural architecture Transformer-XL that enables learning dependency
+beyond a fixed length without disrupting temporal coherence. It consists of a segment-level recurrence mechanism and a
+novel positional encoding scheme. Our method not only enables capturing longer-term dependency, but also resolves the
+context fragmentation problem. As a result, Transformer-XL learns dependency that is 80% longer than RNNs and 450%
+longer than vanilla Transformers, achieves better performance on both short and long sequences, and is up to 1,800+
+times faster than vanilla Transformers during evaluation. Notably, we improve the state-of-the-art results of
+bpc/perplexity to 0.99 on enwiki8, 1.08 on text8, 18.3 on WikiText-103, 21.8 on One Billion Word, and 54.5 on Penn
+Treebank (without finetuning). When trained only on WikiText-103, Transformer-XL manages to generate reasonably
+coherent, novel text articles with thousands of tokens.*
+
+This model was contributed by [thomwolf](https://huggingface.co/thomwolf). The original code can be found [here](https://github.com/kimiyoung/transformer-xl).
+
+## Usage tips
+
+- Transformer-XL uses relative sinusoidal positional embeddings. Padding can be done on the left or on the right. The
+ original implementation trains on SQuAD with padding on the left, therefore the padding defaults are set to left.
+- Transformer-XL is one of the few models that has no sequence length limit.
+- Same as a regular GPT model, but introduces a recurrence mechanism for two consecutive segments (similar to a regular RNNs with two consecutive inputs). In this context, a segment is a number of consecutive tokens (for instance 512) that may span across multiple documents, and segments are fed in order to the model.
+- Basically, the hidden states of the previous segment are concatenated to the current input to compute the attention scores. This allows the model to pay attention to information that was in the previous segment as well as the current one. By stacking multiple attention layers, the receptive field can be increased to multiple previous segments.
+- This changes the positional embeddings to positional relative embeddings (as the regular positional embeddings would give the same results in the current input and the current hidden state at a given position) and needs to make some adjustments in the way attention scores are computed.
+
+
+
+
+TransformerXL does **not** work with *torch.nn.DataParallel* due to a bug in PyTorch, see [issue #36035](https://github.com/pytorch/pytorch/issues/36035)
+
+
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## TransfoXLConfig
+
+[[autodoc]] TransfoXLConfig
+
+## TransfoXLTokenizer
+
+[[autodoc]] TransfoXLTokenizer
+ - save_vocabulary
+
+## TransfoXL specific outputs
+
+[[autodoc]] models.deprecated.transfo_xl.modeling_transfo_xl.TransfoXLModelOutput
+
+[[autodoc]] models.deprecated.transfo_xl.modeling_transfo_xl.TransfoXLLMHeadModelOutput
+
+[[autodoc]] models.deprecated.transfo_xl.modeling_tf_transfo_xl.TFTransfoXLModelOutput
+
+[[autodoc]] models.deprecated.transfo_xl.modeling_tf_transfo_xl.TFTransfoXLLMHeadModelOutput
+
+
+
+
+## TransfoXLModel
+
+[[autodoc]] TransfoXLModel
+ - forward
+
+## TransfoXLLMHeadModel
+
+[[autodoc]] TransfoXLLMHeadModel
+ - forward
+
+## TransfoXLForSequenceClassification
+
+[[autodoc]] TransfoXLForSequenceClassification
+ - forward
+
+
+
+
+## TFTransfoXLModel
+
+[[autodoc]] TFTransfoXLModel
+ - call
+
+## TFTransfoXLLMHeadModel
+
+[[autodoc]] TFTransfoXLLMHeadModel
+ - call
+
+## TFTransfoXLForSequenceClassification
+
+[[autodoc]] TFTransfoXLForSequenceClassification
+ - call
+
+
+
+
+## Internal Layers
+
+[[autodoc]] AdaptiveEmbedding
+
+[[autodoc]] TFAdaptiveEmbedding
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/trocr.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/trocr.md
new file mode 100644
index 0000000000000000000000000000000000000000..c471a13bbd23c5338abda049aa87c5922c46a5b8
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/trocr.md
@@ -0,0 +1,126 @@
+
+
+# TrOCR
+
+## Overview
+
+The TrOCR model was proposed in [TrOCR: Transformer-based Optical Character Recognition with Pre-trained
+Models](https://arxiv.org/abs/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang,
+Zhoujun Li, Furu Wei. TrOCR consists of an image Transformer encoder and an autoregressive text Transformer decoder to
+perform [optical character recognition (OCR)](https://en.wikipedia.org/wiki/Optical_character_recognition).
+
+The abstract from the paper is the following:
+
+*Text recognition is a long-standing research problem for document digitalization. Existing approaches for text recognition
+are usually built based on CNN for image understanding and RNN for char-level text generation. In addition, another language
+model is usually needed to improve the overall accuracy as a post-processing step. In this paper, we propose an end-to-end
+text recognition approach with pre-trained image Transformer and text Transformer models, namely TrOCR, which leverages the
+Transformer architecture for both image understanding and wordpiece-level text generation. The TrOCR model is simple but
+effective, and can be pre-trained with large-scale synthetic data and fine-tuned with human-labeled datasets. Experiments
+show that the TrOCR model outperforms the current state-of-the-art models on both printed and handwritten text recognition
+tasks.*
+
+
+
+ TrOCR architecture. Taken from the original paper.
+
+Please refer to the [`VisionEncoderDecoder`] class on how to use this model.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found
+[here](https://github.com/microsoft/unilm/tree/6f60612e7cc86a2a1ae85c47231507a587ab4e01/trocr).
+
+## Usage tips
+
+- The quickest way to get started with TrOCR is by checking the [tutorial
+ notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/TrOCR), which show how to use the model
+ at inference time as well as fine-tuning on custom data.
+- TrOCR is pre-trained in 2 stages before being fine-tuned on downstream datasets. It achieves state-of-the-art results
+ on both printed (e.g. the [SROIE dataset](https://paperswithcode.com/dataset/sroie) and handwritten (e.g. the [IAM
+ Handwriting dataset](https://fki.tic.heia-fr.ch/databases/iam-handwriting-database>) text recognition tasks. For more
+ information, see the [official models](https://huggingface.co/models?other=trocr>).
+- TrOCR is always used within the [VisionEncoderDecoder](vision-encoder-decoder) framework.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with TrOCR. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- A blog post on [Accelerating Document AI](https://huggingface.co/blog/document-ai) with TrOCR.
+- A blog post on how to [Document AI](https://github.com/philschmid/document-ai-transformers) with TrOCR.
+- A notebook on how to [finetune TrOCR on IAM Handwriting Database using Seq2SeqTrainer](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TrOCR/Fine_tune_TrOCR_on_IAM_Handwriting_Database_using_Seq2SeqTrainer.ipynb).
+- A notebook on [inference with TrOCR](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TrOCR/Inference_with_TrOCR_%2B_Gradio_demo.ipynb) and Gradio demo.
+- A notebook on [finetune TrOCR on the IAM Handwriting Database](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TrOCR/Fine_tune_TrOCR_on_IAM_Handwriting_Database_using_native_PyTorch.ipynb) using native PyTorch.
+- A notebook on [evaluating TrOCR on the IAM test set](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TrOCR/Evaluating_TrOCR_base_handwritten_on_the_IAM_test_set.ipynb).
+
+
+
+- [Casual language modeling](https://huggingface.co/docs/transformers/tasks/language_modeling) task guide.
+
+⚡️ Inference
+
+- An interactive-demo on [TrOCR handwritten character recognition](https://huggingface.co/spaces/nielsr/TrOCR-handwritten).
+
+## Inference
+
+TrOCR's [`VisionEncoderDecoder`] model accepts images as input and makes use of
+[`~generation.GenerationMixin.generate`] to autoregressively generate text given the input image.
+
+The [`ViTImageProcessor`/`DeiTImageProcessor`] class is responsible for preprocessing the input image and
+[`RobertaTokenizer`/`XLMRobertaTokenizer`] decodes the generated target tokens to the target string. The
+[`TrOCRProcessor`] wraps [`ViTImageProcessor`/`DeiTImageProcessor`] and [`RobertaTokenizer`/`XLMRobertaTokenizer`]
+into a single instance to both extract the input features and decode the predicted token ids.
+
+- Step-by-step Optical Character Recognition (OCR)
+
+``` py
+>>> from transformers import TrOCRProcessor, VisionEncoderDecoderModel
+>>> import requests
+>>> from PIL import Image
+
+>>> processor = TrOCRProcessor.from_pretrained("microsoft/trocr-base-handwritten")
+>>> model = VisionEncoderDecoderModel.from_pretrained("microsoft/trocr-base-handwritten")
+
+>>> # load image from the IAM dataset
+>>> url = "https://fki.tic.heia-fr.ch/static/img/a01-122-02.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw).convert("RGB")
+
+>>> pixel_values = processor(image, return_tensors="pt").pixel_values
+>>> generated_ids = model.generate(pixel_values)
+
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+```
+
+See the [model hub](https://huggingface.co/models?filter=trocr) to look for TrOCR checkpoints.
+
+## TrOCRConfig
+
+[[autodoc]] TrOCRConfig
+
+## TrOCRProcessor
+
+[[autodoc]] TrOCRProcessor
+ - __call__
+ - from_pretrained
+ - save_pretrained
+ - batch_decode
+ - decode
+
+## TrOCRForCausalLM
+
+[[autodoc]] TrOCRForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/tvlt.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/tvlt.md
new file mode 100644
index 0000000000000000000000000000000000000000..0a0f50e47315693a684b369d7119315a85fb6883
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/tvlt.md
@@ -0,0 +1,85 @@
+
+
+# TVLT
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The TVLT model was proposed in [TVLT: Textless Vision-Language Transformer](https://arxiv.org/abs/2209.14156)
+by Zineng Tang, Jaemin Cho, Yixin Nie, Mohit Bansal (the first three authors contributed equally). The Textless Vision-Language Transformer (TVLT) is a model that uses raw visual and audio inputs for vision-and-language representation learning, without using text-specific modules such as tokenization or automatic speech recognition (ASR). It can perform various audiovisual and vision-language tasks like retrieval, question answering, etc.
+
+The abstract from the paper is the following:
+
+*In this work, we present the Textless Vision-Language Transformer (TVLT), where homogeneous transformer blocks take raw visual and audio inputs for vision-and-language representation learning with minimal modality-specific design, and do not use text-specific modules such as tokenization or automatic speech recognition (ASR). TVLT is trained by reconstructing masked patches of continuous video frames and audio spectrograms (masked autoencoding) and contrastive modeling to align video and audio. TVLT attains performance comparable to its text-based counterpart on various multimodal tasks, such as visual question answering, image retrieval, video retrieval, and multimodal sentiment analysis, with 28x faster inference speed and only 1/3 of the parameters. Our findings suggest the possibility of learning compact and efficient visual-linguistic representations from low-level visual and audio signals without assuming the prior existence of text.*
+
+
+
+
+
+ TVLT architecture. Taken from the original paper.
+
+The original code can be found [here](https://github.com/zinengtang/TVLT). This model was contributed by [Zineng Tang](https://huggingface.co/ZinengTang).
+
+## Usage tips
+
+- TVLT is a model that takes both `pixel_values` and `audio_values` as input. One can use [`TvltProcessor`] to prepare data for the model.
+ This processor wraps an image processor (for the image/video modality) and an audio feature extractor (for the audio modality) into one.
+- TVLT is trained with images/videos and audios of various sizes: the authors resize and crop the input images/videos to 224 and limit the length of audio spectrogram to 2048. To make batching of videos and audios possible, the authors use a `pixel_mask` that indicates which pixels are real/padding and `audio_mask` that indicates which audio values are real/padding.
+- The design of TVLT is very similar to that of a standard Vision Transformer (ViT) and masked autoencoder (MAE) as in [ViTMAE](vitmae). The difference is that the model includes embedding layers for the audio modality.
+- The PyTorch version of this model is only available in torch 1.10 and higher.
+
+## TvltConfig
+
+[[autodoc]] TvltConfig
+
+## TvltProcessor
+
+[[autodoc]] TvltProcessor
+ - __call__
+
+## TvltImageProcessor
+
+[[autodoc]] TvltImageProcessor
+ - preprocess
+
+## TvltFeatureExtractor
+
+[[autodoc]] TvltFeatureExtractor
+ - __call__
+
+## TvltModel
+
+[[autodoc]] TvltModel
+ - forward
+
+## TvltForPreTraining
+
+[[autodoc]] TvltForPreTraining
+ - forward
+
+## TvltForAudioVisualClassification
+
+[[autodoc]] TvltForAudioVisualClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/tvp.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/tvp.md
new file mode 100644
index 0000000000000000000000000000000000000000..22b400a06c736afd890f8a1a551d83cd573ac5ab
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/tvp.md
@@ -0,0 +1,186 @@
+
+
+# TVP
+
+## Overview
+
+The text-visual prompting (TVP) framework was proposed in the paper [Text-Visual Prompting for Efficient 2D Temporal Video Grounding](https://arxiv.org/abs/2303.04995) by Yimeng Zhang, Xin Chen, Jinghan Jia, Sijia Liu, Ke Ding.
+
+The abstract from the paper is the following:
+
+*In this paper, we study the problem of temporal video grounding (TVG), which aims to predict the starting/ending time points of moments described by a text sentence within a long untrimmed video. Benefiting from fine-grained 3D visual features, the TVG techniques have achieved remarkable progress in recent years. However, the high complexity of 3D convolutional neural networks (CNNs) makes extracting dense 3D visual features time-consuming, which calls for intensive memory and computing resources. Towards efficient TVG, we propose a novel text-visual prompting (TVP) framework, which incorporates optimized perturbation patterns (that we call ‘prompts’) into both visual inputs and textual features of a TVG model. In sharp contrast to 3D CNNs, we show that TVP allows us to effectively co-train vision encoder and language encoder in a 2D TVG model and improves the performance of cross-modal feature fusion using only low-complexity sparse 2D visual features. Further, we propose a Temporal-Distance IoU (TDIoU) loss for efficient learning of TVG. Experiments on two benchmark datasets, Charades-STA and ActivityNet Captions datasets, empirically show that the proposed TVP significantly boosts the performance of 2D TVG (e.g., 9.79% improvement on Charades-STA and 30.77% improvement on ActivityNet Captions) and achieves 5× inference acceleration over TVG using 3D visual features.*
+
+This research addresses temporal video grounding (TVG), which is the process of pinpointing the start and end times of specific events in a long video, as described by a text sentence. Text-visual prompting (TVP), is proposed to enhance TVG. TVP involves integrating specially designed patterns, known as 'prompts', into both the visual (image-based) and textual (word-based) input components of a TVG model. These prompts provide additional spatial-temporal context, improving the model's ability to accurately determine event timings in the video. The approach employs 2D visual inputs in place of 3D ones. Although 3D inputs offer more spatial-temporal detail, they are also more time-consuming to process. The use of 2D inputs with the prompting method aims to provide similar levels of context and accuracy more efficiently.
+
+
+
+ TVP architecture. Taken from the original paper.
+
+This model was contributed by [Jiqing Feng](https://huggingface.co/Jiqing). The original code can be found [here](https://github.com/intel/TVP).
+
+## Usage tips and examples
+
+Prompts are optimized perturbation patterns, which would be added to input video frames or text features. Universal set refers to using the same exact set of prompts for any input, this means that these prompts are added consistently to all video frames and text features, regardless of the input's content.
+
+TVP consists of a visual encoder and cross-modal encoder. A universal set of visual prompts and text prompts to be integrated into sampled video frames and textual features, respectively. Specially, a set of different visual prompts are applied to uniformly-sampled frames of one untrimmed video in order.
+
+The goal of this model is to incorporate trainable prompts into both visual inputs and textual features to temporal video grounding(TVG) problems.
+In principle, one can apply any visual, cross-modal encoder in the proposed architecture.
+
+The [`TvpProcessor`] wraps [`BertTokenizer`] and [`TvpImageProcessor`] into a single instance to both
+encode the text and prepare the images respectively.
+
+The following example shows how to run temporal video grounding using [`TvpProcessor`] and [`TvpForVideoGrounding`].
+```python
+import av
+import cv2
+import numpy as np
+import torch
+from huggingface_hub import hf_hub_download
+from transformers import AutoProcessor, TvpForVideoGrounding
+
+
+def pyav_decode(container, sampling_rate, num_frames, clip_idx, num_clips, target_fps):
+ '''
+ Convert the video from its original fps to the target_fps and decode the video with PyAV decoder.
+ Args:
+ container (container): pyav container.
+ sampling_rate (int): frame sampling rate (interval between two sampled frames).
+ num_frames (int): number of frames to sample.
+ clip_idx (int): if clip_idx is -1, perform random temporal sampling.
+ If clip_idx is larger than -1, uniformly split the video to num_clips
+ clips, and select the clip_idx-th video clip.
+ num_clips (int): overall number of clips to uniformly sample from the given video.
+ target_fps (int): the input video may have different fps, convert it to
+ the target video fps before frame sampling.
+ Returns:
+ frames (tensor): decoded frames from the video. Return None if the no
+ video stream was found.
+ fps (float): the number of frames per second of the video.
+ '''
+ video = container.streams.video[0]
+ fps = float(video.average_rate)
+ clip_size = sampling_rate * num_frames / target_fps * fps
+ delta = max(num_frames - clip_size, 0)
+ start_idx = delta * clip_idx / num_clips
+ end_idx = start_idx + clip_size - 1
+ timebase = video.duration / num_frames
+ video_start_pts = int(start_idx * timebase)
+ video_end_pts = int(end_idx * timebase)
+ seek_offset = max(video_start_pts - 1024, 0)
+ container.seek(seek_offset, any_frame=False, backward=True, stream=video)
+ frames = {}
+ for frame in container.decode(video=0):
+ if frame.pts < video_start_pts:
+ continue
+ frames[frame.pts] = frame
+ if frame.pts > video_end_pts:
+ break
+ frames = [frames[pts] for pts in sorted(frames)]
+ return frames, fps
+
+
+def decode(container, sampling_rate, num_frames, clip_idx, num_clips, target_fps):
+ '''
+ Decode the video and perform temporal sampling.
+ Args:
+ container (container): pyav container.
+ sampling_rate (int): frame sampling rate (interval between two sampled frames).
+ num_frames (int): number of frames to sample.
+ clip_idx (int): if clip_idx is -1, perform random temporal sampling.
+ If clip_idx is larger than -1, uniformly split the video to num_clips
+ clips, and select the clip_idx-th video clip.
+ num_clips (int): overall number of clips to uniformly sample from the given video.
+ target_fps (int): the input video may have different fps, convert it to
+ the target video fps before frame sampling.
+ Returns:
+ frames (tensor): decoded frames from the video.
+ '''
+ assert clip_idx >= -2, "Not a valied clip_idx {}".format(clip_idx)
+ frames, fps = pyav_decode(container, sampling_rate, num_frames, clip_idx, num_clips, target_fps)
+ clip_size = sampling_rate * num_frames / target_fps * fps
+ index = np.linspace(0, clip_size - 1, num_frames)
+ index = np.clip(index, 0, len(frames) - 1).astype(np.int64)
+ frames = np.array([frames[idx].to_rgb().to_ndarray() for idx in index])
+ frames = frames.transpose(0, 3, 1, 2)
+ return frames
+
+
+file = hf_hub_download(repo_id="Intel/tvp_demo", filename="AK2KG.mp4", repo_type="dataset")
+model = TvpForVideoGrounding.from_pretrained("Intel/tvp-base")
+
+decoder_kwargs = dict(
+ container=av.open(file, metadata_errors="ignore"),
+ sampling_rate=1,
+ num_frames=model.config.num_frames,
+ clip_idx=0,
+ num_clips=1,
+ target_fps=3,
+)
+raw_sampled_frms = decode(**decoder_kwargs)
+
+text = "a person is sitting on a bed."
+processor = AutoProcessor.from_pretrained("Intel/tvp-base")
+model_inputs = processor(
+ text=[text], videos=list(raw_sampled_frms), return_tensors="pt", max_text_length=100#, size=size
+)
+
+model_inputs["pixel_values"] = model_inputs["pixel_values"].to(model.dtype)
+output = model(**model_inputs)
+
+def get_video_duration(filename):
+ cap = cv2.VideoCapture(filename)
+ if cap.isOpened():
+ rate = cap.get(5)
+ frame_num = cap.get(7)
+ duration = frame_num/rate
+ return duration
+ return -1
+
+duration = get_video_duration(file)
+start, end = processor.post_process_video_grounding(output.logits, duration)
+
+print(f"The time slot of the video corresponding to the text \"{text}\" is from {start}s to {end}s")
+```
+
+Tips:
+
+- This implementation of TVP uses [`BertTokenizer`] to generate text embeddings and Resnet-50 model to compute visual embeddings.
+- Checkpoints for pre-trained [tvp-base](https://huggingface.co/Intel/tvp-base) is released.
+- Please refer to [Table 2](https://arxiv.org/pdf/2303.04995.pdf) for TVP's performance on Temporal Video Grounding task.
+
+
+## TvpConfig
+
+[[autodoc]] TvpConfig
+
+## TvpImageProcessor
+
+[[autodoc]] TvpImageProcessor
+ - preprocess
+
+## TvpProcessor
+
+[[autodoc]] TvpProcessor
+ - __call__
+
+## TvpModel
+
+[[autodoc]] TvpModel
+ - forward
+
+## TvpForVideoGrounding
+
+[[autodoc]] TvpForVideoGrounding
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/udop.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/udop.md
new file mode 100644
index 0000000000000000000000000000000000000000..614bd2ff4fd7156e094b83f20dfb4a76bf32a4cf
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/udop.md
@@ -0,0 +1,113 @@
+
+
+# UDOP
+
+## Overview
+
+The UDOP model was proposed in [Unifying Vision, Text, and Layout for Universal Document Processing](https://arxiv.org/abs/2212.02623) by Zineng Tang, Ziyi Yang, Guoxin Wang, Yuwei Fang, Yang Liu, Chenguang Zhu, Michael Zeng, Cha Zhang, Mohit Bansal.
+UDOP adopts an encoder-decoder Transformer architecture based on [T5](t5) for document AI tasks like document image classification, document parsing and document visual question answering.
+
+The abstract from the paper is the following:
+
+We propose Universal Document Processing (UDOP), a foundation Document AI model which unifies text, image, and layout modalities together with varied task formats, including document understanding and generation. UDOP leverages the spatial correlation between textual content and document image to model image, text, and layout modalities with one uniform representation. With a novel Vision-Text-Layout Transformer, UDOP unifies pretraining and multi-domain downstream tasks into a prompt-based sequence generation scheme. UDOP is pretrained on both large-scale unlabeled document corpora using innovative self-supervised objectives and diverse labeled data. UDOP also learns to generate document images from text and layout modalities via masked image reconstruction. To the best of our knowledge, this is the first time in the field of document AI that one model simultaneously achieves high-quality neural document editing and content customization. Our method sets the state-of-the-art on 9 Document AI tasks, e.g., document understanding and QA, across diverse data domains like finance reports, academic papers, and websites. UDOP ranks first on the leaderboard of the Document Understanding Benchmark (DUE).*
+
+
+
+ UDOP architecture. Taken from the original paper.
+
+## Usage tips
+
+- In addition to *input_ids*, [`UdopForConditionalGeneration`] also expects the input `bbox`, which are
+ the bounding boxes (i.e. 2D-positions) of the input tokens. These can be obtained using an external OCR engine such
+ as Google's [Tesseract](https://github.com/tesseract-ocr/tesseract) (there's a [Python wrapper](https://pypi.org/project/pytesseract/) available). Each bounding box should be in (x0, y0, x1, y1) format, where (x0, y0) corresponds to the position of the upper left corner in the bounding box, and (x1, y1) represents the
+ position of the lower right corner. Note that one first needs to normalize the bounding boxes to be on a 0-1000
+ scale. To normalize, you can use the following function:
+
+```python
+def normalize_bbox(bbox, width, height):
+ return [
+ int(1000 * (bbox[0] / width)),
+ int(1000 * (bbox[1] / height)),
+ int(1000 * (bbox[2] / width)),
+ int(1000 * (bbox[3] / height)),
+ ]
+```
+
+Here, `width` and `height` correspond to the width and height of the original document in which the token
+occurs. Those can be obtained using the Python Image Library (PIL) library for example, as follows:
+
+```python
+from PIL import Image
+
+# Document can be a png, jpg, etc. PDFs must be converted to images.
+image = Image.open(name_of_your_document).convert("RGB")
+
+width, height = image.size
+```
+
+One can use [`UdopProcessor`] to prepare images and text for the model, which takes care of all of this. By default, this class uses the Tesseract engine to extract a list of words and boxes (coordinates) from a given document. Its functionality is equivalent to that of [`LayoutLMv3Processor`], hence it supports passing either `apply_ocr=False` in case you prefer to use your own OCR engine or `apply_ocr=True` in case you want the default OCR engine to be used. Refer to the [usage guide of LayoutLMv2](layoutlmv2#usage-layoutlmv2processor) regarding all possible use cases (the functionality of `UdopProcessor` is identical).
+
+- If using an own OCR engine of choice, one recommendation is Azure's [Read API](https://learn.microsoft.com/en-us/azure/ai-services/computer-vision/how-to/call-read-api), which supports so-called line segments. Use of segment position embeddings typically results in better performance.
+- At inference time, it's recommended to use the `generate` method to autoregressively generate text given a document image.
+- The model has been pre-trained on both self-supervised and supervised objectives. One can use the various task prefixes (prompts) used during pre-training to test out the out-of-the-box capabilities. For instance, the model can be prompted with "Question answering. What is the date?", as "Question answering." is the task prefix used during pre-training for DocVQA. Refer to the [paper](https://arxiv.org/abs/2212.02623) (table 1) for all task prefixes.
+- One can also fine-tune [`UdopEncoderModel`], which is the encoder-only part of UDOP, which can be seen as a LayoutLMv3-like Transformer encoder. For discriminative tasks, one can just add a linear classifier on top of it and fine-tune it on a labeled dataset.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/microsoft/UDOP).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with UDOP. If
+you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll
+review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- Demo notebooks regarding UDOP can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/UDOP) that show how
+to fine-tune UDOP on a custom dataset as well as inference. 🌎
+- [Document question answering task guide](../tasks/document_question_answering)
+
+## UdopConfig
+
+[[autodoc]] UdopConfig
+
+## UdopTokenizer
+
+[[autodoc]] UdopTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## UdopTokenizerFast
+
+[[autodoc]] UdopTokenizerFast
+
+## UdopProcessor
+
+[[autodoc]] UdopProcessor
+ - __call__
+
+## UdopModel
+
+[[autodoc]] UdopModel
+ - forward
+
+## UdopForConditionalGeneration
+
+[[autodoc]] UdopForConditionalGeneration
+ - forward
+
+## UdopEncoderModel
+
+[[autodoc]] UdopEncoderModel
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/ul2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/ul2.md
new file mode 100644
index 0000000000000000000000000000000000000000..f4d01c40b0c10944e5ddb3451f355e4c95bf2d9a
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/ul2.md
@@ -0,0 +1,43 @@
+
+
+# UL2
+
+## Overview
+
+The T5 model was presented in [Unifying Language Learning Paradigms](https://arxiv.org/pdf/2205.05131v1.pdf) by Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler.
+
+The abstract from the paper is the following:
+
+*Existing pre-trained models are generally geared towards a particular class of problems. To date, there seems to be still no consensus on what the right architecture and pre-training setup should be. This paper presents a unified framework for pre-training models that are universally effective across datasets and setups. We begin by disentangling architectural archetypes with pre-training objectives -- two concepts that are commonly conflated. Next, we present a generalized and unified perspective for self-supervision in NLP and show how different pre-training objectives can be cast as one another and how interpolating between different objectives can be effective. We then propose Mixture-of-Denoisers (MoD), a pre-training objective that combines diverse pre-training paradigms together. We furthermore introduce a notion of mode switching, wherein downstream fine-tuning is associated with specific pre-training schemes. We conduct extensive ablative experiments to compare multiple pre-training objectives and find that our method pushes the Pareto-frontier by outperforming T5 and/or GPT-like models across multiple diverse setups. Finally, by scaling our model up to 20B parameters, we achieve SOTA performance on 50 well-established supervised NLP tasks ranging from language generation (with automated and human evaluation), language understanding, text classification, question answering, commonsense reasoning, long text reasoning, structured knowledge grounding and information retrieval. Our model also achieve strong results at in-context learning, outperforming 175B GPT-3 on zero-shot SuperGLUE and tripling the performance of T5-XXL on one-shot summarization.*
+
+This model was contributed by [DanielHesslow](https://huggingface.co/Seledorn). The original code can be found [here](https://github.com/google-research/google-research/tree/master/ul2).
+
+## Usage tips
+
+- UL2 is an encoder-decoder model pre-trained on a mixture of denoising functions as well as fine-tuned on an array of downstream tasks.
+- UL2 has the same architecture as [T5v1.1](t5v1.1) but uses the Gated-SiLU activation function instead of Gated-GELU.
+- The authors release checkpoints of one architecture which can be seen [here](https://huggingface.co/google/ul2)
+
+
+
+As UL2 has the same architecture as T5v1.1, refer to [T5's documentation page](t5) for API reference, tips, code examples and notebooks.
+
+
+
+
+
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/umt5.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/umt5.md
new file mode 100644
index 0000000000000000000000000000000000000000..b9f86a0304e89234e9c6be31d854fd6851e050d7
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/umt5.md
@@ -0,0 +1,112 @@
+
+
+# UMT5
+
+
+
+## Overview
+
+The UMT5 model was proposed in [UniMax: Fairer and More Effective Language Sampling for Large-Scale Multilingual Pretraining](https://openreview.net/forum?id=kXwdL1cWOAi) by Hyung Won Chung, Xavier Garcia, Adam Roberts, Yi Tay, Orhan Firat, Sharan Narang, Noah Constant.
+
+The abstract from the paper is the following:
+
+*Pretrained multilingual large language models have typically used heuristic temperature-based sampling to balance between different languages. However previous work has not systematically evaluated the efficacy of different pretraining language distributions across model scales. In this paper, we propose a new sampling method, UniMax, that delivers more uniform coverage of head languages while mitigating overfitting on tail languages by explicitly capping the number of repeats over each language's corpus. We perform an extensive series of ablations testing a range of sampling strategies on a suite of multilingual benchmarks, while varying model scale. We find that UniMax outperforms standard temperature-based sampling, and the benefits persist as scale increases. As part of our contribution, we release: (i) an improved and refreshed mC4 multilingual corpus consisting of 29 trillion characters across 107 languages, and (ii) a suite of pretrained umT5 model checkpoints trained with UniMax sampling.*
+
+Google has released the following variants:
+
+- [google/umt5-small](https://huggingface.co/google/umt5-small)
+- [google/umt5-base](https://huggingface.co/google/umt5-base)
+- [google/umt5-xl](https://huggingface.co/google/umt5-xl)
+- [google/umt5-xxl](https://huggingface.co/google/umt5-xxl).
+
+This model was contributed by [agemagician](https://huggingface.co/agemagician) and [stefan-it](https://huggingface.co/stefan-it). The original code can be
+found [here](https://github.com/google-research/t5x).
+
+## Usage tips
+
+- UMT5 was only pre-trained on [mC4](https://huggingface.co/datasets/mc4) excluding any supervised training.
+Therefore, this model has to be fine-tuned before it is usable on a downstream task, unlike the original T5 model.
+- Since umT5 was pre-trained in an unsupervised manner, there's no real advantage to using a task prefix during single-task
+fine-tuning. If you are doing multi-task fine-tuning, you should use a prefix.
+
+## Differences with mT5?
+`UmT5` is based on mT5, with a non-shared relative positional bias that is computed for each layer. This means that the model set `has_relative_bias` for each layer.
+The conversion script is also different because the model was saved in t5x's latest checkpointing format.
+
+# Sample usage
+
+```python
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("google/umt5-small")
+>>> tokenizer = AutoTokenizer.from_pretrained("google/umt5-small")
+
+>>> inputs = tokenizer(
+... "A walks into a bar and orders a with pinch of .",
+... return_tensors="pt",
+... )
+>>> outputs = model.generate(**inputs)
+>>> print(tokenizer.batch_decode(outputs))
+['nyone who drink a alcohol A A. This I']
+```
+
+
+
+Refer to [T5's documentation page](t5) for more tips, code examples and notebooks.
+
+
+## UMT5Config
+
+[[autodoc]] UMT5Config
+
+## UMT5Model
+
+[[autodoc]] UMT5Model
+ - forward
+
+## UMT5ForConditionalGeneration
+
+[[autodoc]] UMT5ForConditionalGeneration
+ - forward
+
+## UMT5EncoderModel
+
+[[autodoc]] UMT5EncoderModel
+ - forward
+
+## UMT5ForSequenceClassification
+
+[[autodoc]] UMT5ForSequenceClassification
+ - forward
+
+## UMT5ForTokenClassification
+
+[[autodoc]] UMT5ForTokenClassification
+ - forward
+
+## UMT5ForQuestionAnswering
+
+[[autodoc]] UMT5ForQuestionAnswering
+ - forward
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/unispeech-sat.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/unispeech-sat.md
new file mode 100644
index 0000000000000000000000000000000000000000..3f0bbcc79323f23271c555fca6fe4c0864ad69ed
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/unispeech-sat.md
@@ -0,0 +1,92 @@
+
+
+# UniSpeech-SAT
+
+## Overview
+
+The UniSpeech-SAT model was proposed in [UniSpeech-SAT: Universal Speech Representation Learning with Speaker Aware
+Pre-Training](https://arxiv.org/abs/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen,
+Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu .
+
+The abstract from the paper is the following:
+
+*Self-supervised learning (SSL) is a long-standing goal for speech processing, since it utilizes large-scale unlabeled
+data and avoids extensive human labeling. Recent years witness great successes in applying self-supervised learning in
+speech recognition, while limited exploration was attempted in applying SSL for modeling speaker characteristics. In
+this paper, we aim to improve the existing SSL framework for speaker representation learning. Two methods are
+introduced for enhancing the unsupervised speaker information extraction. First, we apply the multi-task learning to
+the current SSL framework, where we integrate the utterance-wise contrastive loss with the SSL objective function.
+Second, for better speaker discrimination, we propose an utterance mixing strategy for data augmentation, where
+additional overlapped utterances are created unsupervisedly and incorporate during training. We integrate the proposed
+methods into the HuBERT framework. Experiment results on SUPERB benchmark show that the proposed system achieves
+state-of-the-art performance in universal representation learning, especially for speaker identification oriented
+tasks. An ablation study is performed verifying the efficacy of each proposed method. Finally, we scale up training
+dataset to 94 thousand hours public audio data and achieve further performance improvement in all SUPERB tasks.*
+
+This model was contributed by [patrickvonplaten](https://huggingface.co/patrickvonplaten). The Authors' code can be
+found [here](https://github.com/microsoft/UniSpeech/tree/main/UniSpeech-SAT).
+
+## Usage tips
+
+- UniSpeechSat is a speech model that accepts a float array corresponding to the raw waveform of the speech signal.
+ Please use [`Wav2Vec2Processor`] for the feature extraction.
+- UniSpeechSat model can be fine-tuned using connectionist temporal classification (CTC) so the model output has to be
+ decoded using [`Wav2Vec2CTCTokenizer`].
+- UniSpeechSat performs especially well on speaker verification, speaker identification, and speaker diarization tasks.
+
+## Resources
+
+- [Audio classification task guide](../tasks/audio_classification)
+- [Automatic speech recognition task guide](../tasks/asr)
+
+## UniSpeechSatConfig
+
+[[autodoc]] UniSpeechSatConfig
+
+## UniSpeechSat specific outputs
+
+[[autodoc]] models.unispeech_sat.modeling_unispeech_sat.UniSpeechSatForPreTrainingOutput
+
+## UniSpeechSatModel
+
+[[autodoc]] UniSpeechSatModel
+ - forward
+
+## UniSpeechSatForCTC
+
+[[autodoc]] UniSpeechSatForCTC
+ - forward
+
+## UniSpeechSatForSequenceClassification
+
+[[autodoc]] UniSpeechSatForSequenceClassification
+ - forward
+
+## UniSpeechSatForAudioFrameClassification
+
+[[autodoc]] UniSpeechSatForAudioFrameClassification
+ - forward
+
+## UniSpeechSatForXVector
+
+[[autodoc]] UniSpeechSatForXVector
+ - forward
+
+## UniSpeechSatForPreTraining
+
+[[autodoc]] UniSpeechSatForPreTraining
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/unispeech.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/unispeech.md
new file mode 100644
index 0000000000000000000000000000000000000000..2b2b13bed52c17890f63e0e86d88a13907eb29e5
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/unispeech.md
@@ -0,0 +1,77 @@
+
+
+# UniSpeech
+
+## Overview
+
+The UniSpeech model was proposed in [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://arxiv.org/abs/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael
+Zeng, Xuedong Huang .
+
+The abstract from the paper is the following:
+
+*In this paper, we propose a unified pre-training approach called UniSpeech to learn speech representations with both
+unlabeled and labeled data, in which supervised phonetic CTC learning and phonetically-aware contrastive
+self-supervised learning are conducted in a multi-task learning manner. The resultant representations can capture
+information more correlated with phonetic structures and improve the generalization across languages and domains. We
+evaluate the effectiveness of UniSpeech for cross-lingual representation learning on public CommonVoice corpus. The
+results show that UniSpeech outperforms self-supervised pretraining and supervised transfer learning for speech
+recognition by a maximum of 13.4% and 17.8% relative phone error rate reductions respectively (averaged over all
+testing languages). The transferability of UniSpeech is also demonstrated on a domain-shift speech recognition task,
+i.e., a relative word error rate reduction of 6% against the previous approach.*
+
+This model was contributed by [patrickvonplaten](https://huggingface.co/patrickvonplaten). The Authors' code can be
+found [here](https://github.com/microsoft/UniSpeech/tree/main/UniSpeech).
+
+## Usage tips
+
+- UniSpeech is a speech model that accepts a float array corresponding to the raw waveform of the speech signal. Please
+ use [`Wav2Vec2Processor`] for the feature extraction.
+- UniSpeech model can be fine-tuned using connectionist temporal classification (CTC) so the model output has to be
+ decoded using [`Wav2Vec2CTCTokenizer`].
+
+## Resources
+
+- [Audio classification task guide](../tasks/audio_classification)
+- [Automatic speech recognition task guide](../tasks/asr)
+
+## UniSpeechConfig
+
+[[autodoc]] UniSpeechConfig
+
+## UniSpeech specific outputs
+
+[[autodoc]] models.unispeech.modeling_unispeech.UniSpeechForPreTrainingOutput
+
+## UniSpeechModel
+
+[[autodoc]] UniSpeechModel
+ - forward
+
+## UniSpeechForCTC
+
+[[autodoc]] UniSpeechForCTC
+ - forward
+
+## UniSpeechForSequenceClassification
+
+[[autodoc]] UniSpeechForSequenceClassification
+ - forward
+
+## UniSpeechForPreTraining
+
+[[autodoc]] UniSpeechForPreTraining
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/univnet.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/univnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..45bd94732773ae48ee39dc847019a50a4a036d73
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/univnet.md
@@ -0,0 +1,80 @@
+
+
+# UnivNet
+
+## Overview
+
+The UnivNet model was proposed in [UnivNet: A Neural Vocoder with Multi-Resolution Spectrogram Discriminators for High-Fidelity Waveform Generation](https://arxiv.org/abs/2106.07889) by Won Jang, Dan Lim, Jaesam Yoon, Bongwan Kin, and Juntae Kim.
+The UnivNet model is a generative adversarial network (GAN) trained to synthesize high fidelity speech waveforms. The UnivNet model shared in `transformers` is the *generator*, which maps a conditioning log-mel spectrogram and optional noise sequence to a speech waveform (e.g. a vocoder). Only the generator is required for inference. The *discriminator* used to train the `generator` is not implemented.
+
+The abstract from the paper is the following:
+
+*Most neural vocoders employ band-limited mel-spectrograms to generate waveforms. If full-band spectral features are used as the input, the vocoder can be provided with as much acoustic information as possible. However, in some models employing full-band mel-spectrograms, an over-smoothing problem occurs as part of which non-sharp spectrograms are generated. To address this problem, we propose UnivNet, a neural vocoder that synthesizes high-fidelity waveforms in real time. Inspired by works in the field of voice activity detection, we added a multi-resolution spectrogram discriminator that employs multiple linear spectrogram magnitudes computed using various parameter sets. Using full-band mel-spectrograms as input, we expect to generate high-resolution signals by adding a discriminator that employs spectrograms of multiple resolutions as the input. In an evaluation on a dataset containing information on hundreds of speakers, UnivNet obtained the best objective and subjective results among competing models for both seen and unseen speakers. These results, including the best subjective score for text-to-speech, demonstrate the potential for fast adaptation to new speakers without a need for training from scratch.*
+
+Tips:
+
+- The `noise_sequence` argument for [`UnivNetModel.forward`] should be standard Gaussian noise (such as from `torch.randn`) of shape `([batch_size], noise_length, model.config.model_in_channels)`, where `noise_length` should match the length dimension (dimension 1) of the `input_features` argument. If not supplied, it will be randomly generated; a `torch.Generator` can be supplied to the `generator` argument so that the forward pass can be reproduced. (Note that [`UnivNetFeatureExtractor`] will return generated noise by default, so it shouldn't be necessary to generate `noise_sequence` manually.)
+- Padding added by [`UnivNetFeatureExtractor`] can be removed from the [`UnivNetModel`] output through the [`UnivNetFeatureExtractor.batch_decode`] method, as shown in the usage example below.
+- Padding the end of each waveform with silence can reduce artifacts at the end of the generated audio sample. This can be done by supplying `pad_end = True` to [`UnivNetFeatureExtractor.__call__`]. See [this issue](https://github.com/seungwonpark/melgan/issues/8) for more details.
+
+Usage Example:
+
+```python
+import torch
+from scipy.io.wavfile import write
+from datasets import Audio, load_dataset
+
+from transformers import UnivNetFeatureExtractor, UnivNetModel
+
+model_id_or_path = "dg845/univnet-dev"
+model = UnivNetModel.from_pretrained(model_id_or_path)
+feature_extractor = UnivNetFeatureExtractor.from_pretrained(model_id_or_path)
+
+ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+# Resample the audio to the model and feature extractor's sampling rate.
+ds = ds.cast_column("audio", Audio(sampling_rate=feature_extractor.sampling_rate))
+# Pad the end of the converted waveforms to reduce artifacts at the end of the output audio samples.
+inputs = feature_extractor(
+ ds[0]["audio"]["array"], sampling_rate=ds[0]["audio"]["sampling_rate"], pad_end=True, return_tensors="pt"
+)
+
+with torch.no_grad():
+ audio = model(**inputs)
+
+# Remove the extra padding at the end of the output.
+audio = feature_extractor.batch_decode(**audio)[0]
+# Convert to wav file
+write("sample_audio.wav", feature_extractor.sampling_rate, audio)
+```
+
+This model was contributed by [dg845](https://huggingface.co/dg845).
+To the best of my knowledge, there is no official code release, but an unofficial implementation can be found at [maum-ai/univnet](https://github.com/maum-ai/univnet) with pretrained checkpoints [here](https://github.com/maum-ai/univnet#pre-trained-model).
+
+
+## UnivNetConfig
+
+[[autodoc]] UnivNetConfig
+
+## UnivNetFeatureExtractor
+
+[[autodoc]] UnivNetFeatureExtractor
+ - __call__
+
+## UnivNetModel
+
+[[autodoc]] UnivNetModel
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/upernet.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/upernet.md
new file mode 100644
index 0000000000000000000000000000000000000000..418c3ef1786b52d5f265336994dabf93a12cf8af
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/upernet.md
@@ -0,0 +1,79 @@
+
+
+# UPerNet
+
+## Overview
+
+The UPerNet model was proposed in [Unified Perceptual Parsing for Scene Understanding](https://arxiv.org/abs/1807.10221)
+by Tete Xiao, Yingcheng Liu, Bolei Zhou, Yuning Jiang, Jian Sun. UPerNet is a general framework to effectively segment
+a wide range of concepts from images, leveraging any vision backbone like [ConvNeXt](convnext) or [Swin](swin).
+
+The abstract from the paper is the following:
+
+*Humans recognize the visual world at multiple levels: we effortlessly categorize scenes and detect objects inside, while also identifying the textures and surfaces of the objects along with their different compositional parts. In this paper, we study a new task called Unified Perceptual Parsing, which requires the machine vision systems to recognize as many visual concepts as possible from a given image. A multi-task framework called UPerNet and a training strategy are developed to learn from heterogeneous image annotations. We benchmark our framework on Unified Perceptual Parsing and show that it is able to effectively segment a wide range of concepts from images. The trained networks are further applied to discover visual knowledge in natural scenes.*
+
+
+
+ UPerNet framework. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code is based on OpenMMLab's mmsegmentation [here](https://github.com/open-mmlab/mmsegmentation/blob/master/mmseg/models/decode_heads/uper_head.py).
+
+## Usage examples
+
+UPerNet is a general framework for semantic segmentation. It can be used with any vision backbone, like so:
+
+```py
+from transformers import SwinConfig, UperNetConfig, UperNetForSemanticSegmentation
+
+backbone_config = SwinConfig(out_features=["stage1", "stage2", "stage3", "stage4"])
+
+config = UperNetConfig(backbone_config=backbone_config)
+model = UperNetForSemanticSegmentation(config)
+```
+
+To use another vision backbone, like [ConvNeXt](convnext), simply instantiate the model with the appropriate backbone:
+
+```py
+from transformers import ConvNextConfig, UperNetConfig, UperNetForSemanticSegmentation
+
+backbone_config = ConvNextConfig(out_features=["stage1", "stage2", "stage3", "stage4"])
+
+config = UperNetConfig(backbone_config=backbone_config)
+model = UperNetForSemanticSegmentation(config)
+```
+
+Note that this will randomly initialize all the weights of the model.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with UPerNet.
+
+- Demo notebooks for UPerNet can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/UPerNet).
+- [`UperNetForSemanticSegmentation`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/semantic-segmentation) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/semantic_segmentation.ipynb).
+- See also: [Semantic segmentation task guide](../tasks/semantic_segmentation)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## UperNetConfig
+
+[[autodoc]] UperNetConfig
+
+## UperNetForSemanticSegmentation
+
+[[autodoc]] UperNetForSemanticSegmentation
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/van.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/van.md
new file mode 100644
index 0000000000000000000000000000000000000000..2fb8475ce72f3285904df831617a8450d3300776
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/van.md
@@ -0,0 +1,72 @@
+
+
+# VAN
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.30.0.
+You can do so by running the following command: `pip install -U transformers==4.30.0`.
+
+
+
+## Overview
+
+The VAN model was proposed in [Visual Attention Network](https://arxiv.org/abs/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
+
+This paper introduces a new attention layer based on convolution operations able to capture both local and distant relationships. This is done by combining normal and large kernel convolution layers. The latter uses a dilated convolution to capture distant correlations.
+
+The abstract from the paper is the following:
+
+*While originally designed for natural language processing tasks, the self-attention mechanism has recently taken various computer vision areas by storm. However, the 2D nature of images brings three challenges for applying self-attention in computer vision. (1) Treating images as 1D sequences neglects their 2D structures. (2) The quadratic complexity is too expensive for high-resolution images. (3) It only captures spatial adaptability but ignores channel adaptability. In this paper, we propose a novel large kernel attention (LKA) module to enable self-adaptive and long-range correlations in self-attention while avoiding the above issues. We further introduce a novel neural network based on LKA, namely Visual Attention Network (VAN). While extremely simple, VAN outperforms the state-of-the-art vision transformers and convolutional neural networks with a large margin in extensive experiments, including image classification, object detection, semantic segmentation, instance segmentation, etc. Code is available at [this https URL](https://github.com/Visual-Attention-Network/VAN-Classification).*
+
+Tips:
+
+- VAN does not have an embedding layer, thus the `hidden_states` will have a length equal to the number of stages.
+
+The figure below illustrates the architecture of a Visual Attention Layer. Taken from the [original paper](https://arxiv.org/abs/2202.09741).
+
+
+
+This model was contributed by [Francesco](https://huggingface.co/Francesco). The original code can be found [here](https://github.com/Visual-Attention-Network/VAN-Classification).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with VAN.
+
+
+
+- [`VanForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## VanConfig
+
+[[autodoc]] VanConfig
+
+## VanModel
+
+[[autodoc]] VanModel
+ - forward
+
+## VanForImageClassification
+
+[[autodoc]] VanForImageClassification
+ - forward
+
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/video_llava.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/video_llava.md
new file mode 100644
index 0000000000000000000000000000000000000000..a3ba1258ecfa061fc63bb7971e5dbb1e8833c16b
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/video_llava.md
@@ -0,0 +1,215 @@
+
+
+# Video-LLaVA
+
+## Overview
+
+Video-LLaVa is an open-source multimodal LLM trained by fine-tuning LlamA/Vicuna on multimodal instruction-following data generated by Llava1.5 and VideChat. It is an auto-regressive language model, based on the transformer architecture. Video-LLaVa unifies visual representations to the language feature space, and enables an LLM to perform visual reasoning capabilities on both images and videos simultaneously.
+
+
+The Video-LLaVA model was proposed in [Video-LLaVA: Learning United Visual Representation by Alignment Before Projection](https://arxiv.org/abs/2311.10122) by Bin Lin, Yang Ye, Bin Zhu, Jiaxi Cui, Munang Ning, Peng Jin, Li Yuan.
+
+The abstract from the paper is the following:
+
+*The Large Vision-Language Model (LVLM) has enhanced the performance of various downstream tasks in
+visual-language understanding. Most existing approaches
+encode images and videos into separate feature spaces,
+which are then fed as inputs to large language models.
+However, due to the lack of unified tokenization for images and videos, namely misalignment before projection, it
+becomes challenging for a Large Language Model (LLM)
+to learn multi-modal interactions from several poor projection layers. In this work, we unify visual representation into the language feature space to advance the foundational LLM towards a unified LVLM. As a result, we establish a simple but robust LVLM baseline, Video-LLaVA,
+which learns from a mixed dataset of images and videos,
+mutually enhancing each other. Video-LLaVA achieves superior performances on a broad range of 9 image benchmarks across 5 image question-answering datasets and 4
+image benchmark toolkits. Additionally, our Video-LLaVA
+also outperforms Video-ChatGPT by 5.8%, 9.9%, 18.6%,
+and 10.1% on MSRVTT, MSVD, TGIF, and ActivityNet, respectively. Notably, extensive experiments demonstrate that
+Video-LLaVA mutually benefits images and videos within
+a unified visual representation, outperforming models designed specifically for images or videos. We aim for this
+work to provide modest insights into the multi-modal inputs
+for the LLM*
+
+## Usage tips:
+
+- We advise users to use padding_side="left" when computing batched generation as it leads to more accurate results. Simply make sure to call processor.tokenizer.padding_side = "left" before generating.
+
+- Note the model has not been explicitly trained to process multiple images/videos in the same prompt, although this is technically possible, you may experience inaccurate results.
+
+- Note that the video inputs should have exactly 8 frames at the input, since the models were trained in that setting.
+
+This model was contributed by [RaushanTurganbay](https://huggingface.co/RaushanTurganbay).
+The original code can be found [here](https://github.com/PKU-YuanGroup/Video-LLaVA).
+
+
+> [!NOTE]
+> LLaVA models after release v4.46 will raise warnings about adding `processor.patch_size = {{patch_size}}`, `processor.num_additional_image_tokens = {{num_additional_image_tokens}}` and processor.vision_feature_select_strategy = {{vision_feature_select_strategy}}`. It is strongly recommended to add the attributes to the processor if you own the model checkpoint, or open a PR if it is not owned by you.
+Adding these attributes means that LLaVA will try to infer the number of image tokens required per image and expand the text with as many `` placeholders as there will be tokens. Usually it is around 500 tokens per image, so make sure that the text is not truncated as otherwise there will be failure when merging the embeddings.
+The attributes can be obtained from model config, as `model.config.vision_config.patch_size` or `model.config.vision_feature_select_strategy`. The `num_additional_image_tokens` should be `1` if the vision backbone adds a CLS token or `0` if nothing extra is added to the vision patches.
+
+
+## Usage example
+
+### Single Media Mode
+
+The model can accept both images and videos as input. Here's an example code for inference in half-precision (`torch.float16`):
+
+```python
+import av
+import torch
+import numpy as np
+from transformers import VideoLlavaForConditionalGeneration, VideoLlavaProcessor
+
+def read_video_pyav(container, indices):
+ '''
+ Decode the video with PyAV decoder.
+ Args:
+ container (`av.container.input.InputContainer`): PyAV container.
+ indices (`List[int]`): List of frame indices to decode.
+ Returns:
+ result (np.ndarray): np array of decoded frames of shape (num_frames, height, width, 3).
+ '''
+ frames = []
+ container.seek(0)
+ start_index = indices[0]
+ end_index = indices[-1]
+ for i, frame in enumerate(container.decode(video=0)):
+ if i > end_index:
+ break
+ if i >= start_index and i in indices:
+ frames.append(frame)
+ return np.stack([x.to_ndarray(format="rgb24") for x in frames])
+
+# Load the model in half-precision
+model = VideoLlavaForConditionalGeneration.from_pretrained("LanguageBind/Video-LLaVA-7B-hf", torch_dtype=torch.float16, device_map="auto")
+processor = VideoLlavaProcessor.from_pretrained("LanguageBind/Video-LLaVA-7B-hf")
+
+# Load the video as an np.arrau, sampling uniformly 8 frames
+video_path = hf_hub_download(repo_id="raushan-testing-hf/videos-test", filename="sample_demo_1.mp4", repo_type="dataset")
+container = av.open(video_path)
+total_frames = container.streams.video[0].frames
+indices = np.arange(0, total_frames, total_frames / 8).astype(int)
+video = read_video_pyav(container, indices)
+
+# For better results, we recommend to prompt the model in the following format
+prompt = "USER:
 +
+
+
 +
+
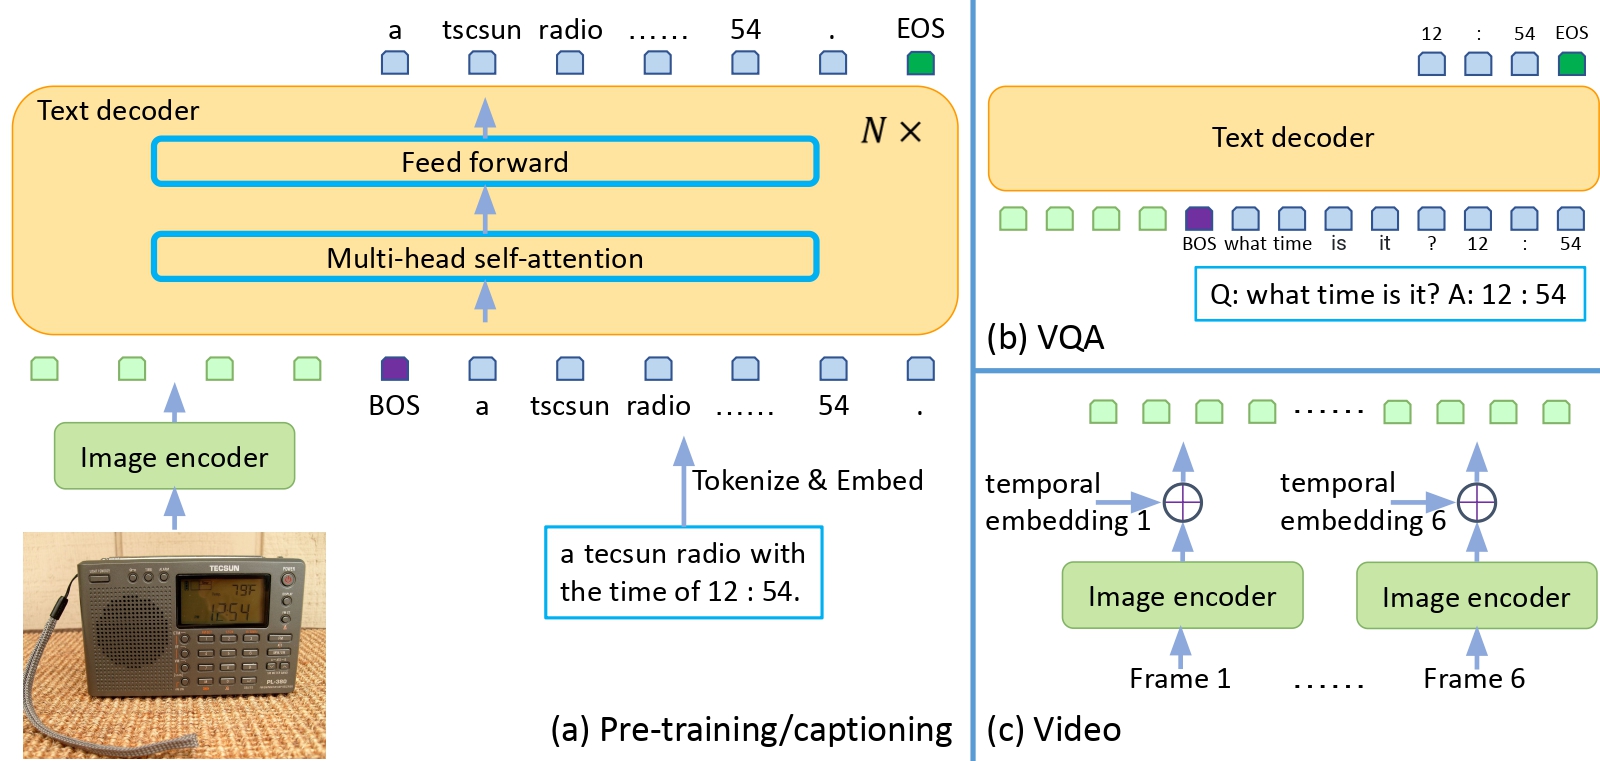 +
+ GIT architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/microsoft/GenerativeImage2Text).
+
+## Usage tips
+
+- GIT is implemented in a very similar way to GPT-2, the only difference being that the model is also conditioned on `pixel_values`.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with GIT.
+
+- Demo notebooks regarding inference + fine-tuning GIT on custom data can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/GIT).
+- See also: [Causal language modeling task guide](../tasks/language_modeling)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we will review it.
+The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## GitVisionConfig
+
+[[autodoc]] GitVisionConfig
+
+## GitVisionModel
+
+[[autodoc]] GitVisionModel
+ - forward
+
+## GitConfig
+
+[[autodoc]] GitConfig
+ - all
+
+## GitProcessor
+
+[[autodoc]] GitProcessor
+ - __call__
+
+## GitModel
+
+[[autodoc]] GitModel
+ - forward
+
+## GitForCausalLM
+
+[[autodoc]] GitForCausalLM
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/glm.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/glm.md
new file mode 100644
index 0000000000000000000000000000000000000000..be0b367b62ec0264373c756ca708f3bb22070973
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/glm.md
@@ -0,0 +1,99 @@
+
+
+# GLM
+
+## Overview
+
+The GLM Model was proposed
+in [ChatGLM: A Family of Large Language Models from GLM-130B to GLM-4 All Tools](https://arxiv.org/html/2406.12793v1)
+by GLM Team, THUDM & ZhipuAI.
+
+The abstract from the paper is the following:
+
+*We introduce ChatGLM, an evolving family of large language models that we have been developing over time. This report
+primarily focuses on the GLM-4 language series, which includes GLM-4, GLM-4-Air, and GLM-4-9B. They represent our most
+capable models that are trained with all the insights and lessons gained from the preceding three generations of
+ChatGLM. To date, the GLM-4 models are pre-trained on ten trillions of tokens mostly in Chinese and English, along with
+a small set of corpus from 24 languages, and aligned primarily for Chinese and English usage. The high-quality alignment
+is achieved via a multi-stage post-training process, which involves supervised fine-tuning and learning from human
+feedback. Evaluations show that GLM-4 1) closely rivals or outperforms GPT-4 in terms of general metrics such as MMLU,
+GSM8K, MATH, BBH, GPQA, and HumanEval, 2) gets close to GPT-4-Turbo in instruction following as measured by IFEval, 3)
+matches GPT-4 Turbo (128K) and Claude 3 for long context tasks, and 4) outperforms GPT-4 in Chinese alignments as
+measured by AlignBench. The GLM-4 All Tools model is further aligned to understand user intent and autonomously decide
+when and which tool(s) to use—including web browser, Python interpreter, text-to-image model, and user-defined
+functions—to effectively complete complex tasks. In practical applications, it matches and even surpasses GPT-4 All
+Tools in tasks like accessing online information via web browsing and solving math problems using Python interpreter.
+Over the course, we have open-sourced a series of models, including ChatGLM-6B (three generations), GLM-4-9B (128K, 1M),
+GLM-4V-9B, WebGLM, and CodeGeeX, attracting over 10 million downloads on Hugging face in the year 2023 alone.*
+
+Tips:
+
+- This model was contributed by [THUDM](https://huggingface.co/THUDM). The most recent code can be
+ found [here](https://github.com/thudm/GLM-4).
+
+
+## Usage tips
+
+`GLM-4` can be found on the [Huggingface Hub](https://huggingface.co/collections/THUDM/glm-4-665fcf188c414b03c2f7e3b7)
+
+In the following, we demonstrate how to use `glm-4-9b-chat` for the inference. Note that we have used the ChatML format for dialog, in this demo we show how to leverage `apply_chat_template` for this purpose.
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+>>> device = "cuda" # the device to load the model onto
+
+>>> model = AutoModelForCausalLM.from_pretrained("THUDM/glm-4-9b-chat", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("THUDM/glm-4-9b-chat")
+
+>>> prompt = "Give me a short introduction to large language model."
+
+>>> messages = [{"role": "user", "content": prompt}]
+
+>>> text = tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
+
+>>> model_inputs = tokenizer([text], return_tensors="pt").to(device)
+
+>>> generated_ids = model.generate(model_inputs.input_ids, max_new_tokens=512, do_sample=True)
+
+>>> generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(model_inputs.input_ids, generated_ids)]
+
+>>> response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+```
+
+## GlmConfig
+
+[[autodoc]] GlmConfig
+
+## GlmModel
+
+[[autodoc]] GlmModel
+ - forward
+
+## GlmForCausalLM
+
+[[autodoc]] GlmForCausalLM
+ - forward
+
+## GlmForSequenceClassification
+
+[[autodoc]] GlmForSequenceClassification
+ - forward
+
+## GlmForTokenClassification
+
+[[autodoc]] GlmForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/glpn.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/glpn.md
new file mode 100644
index 0000000000000000000000000000000000000000..b57d1a7ccdda7f3814a401e832ebc0a13bfdfd49
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/glpn.md
@@ -0,0 +1,72 @@
+
+
+# GLPN
+
+
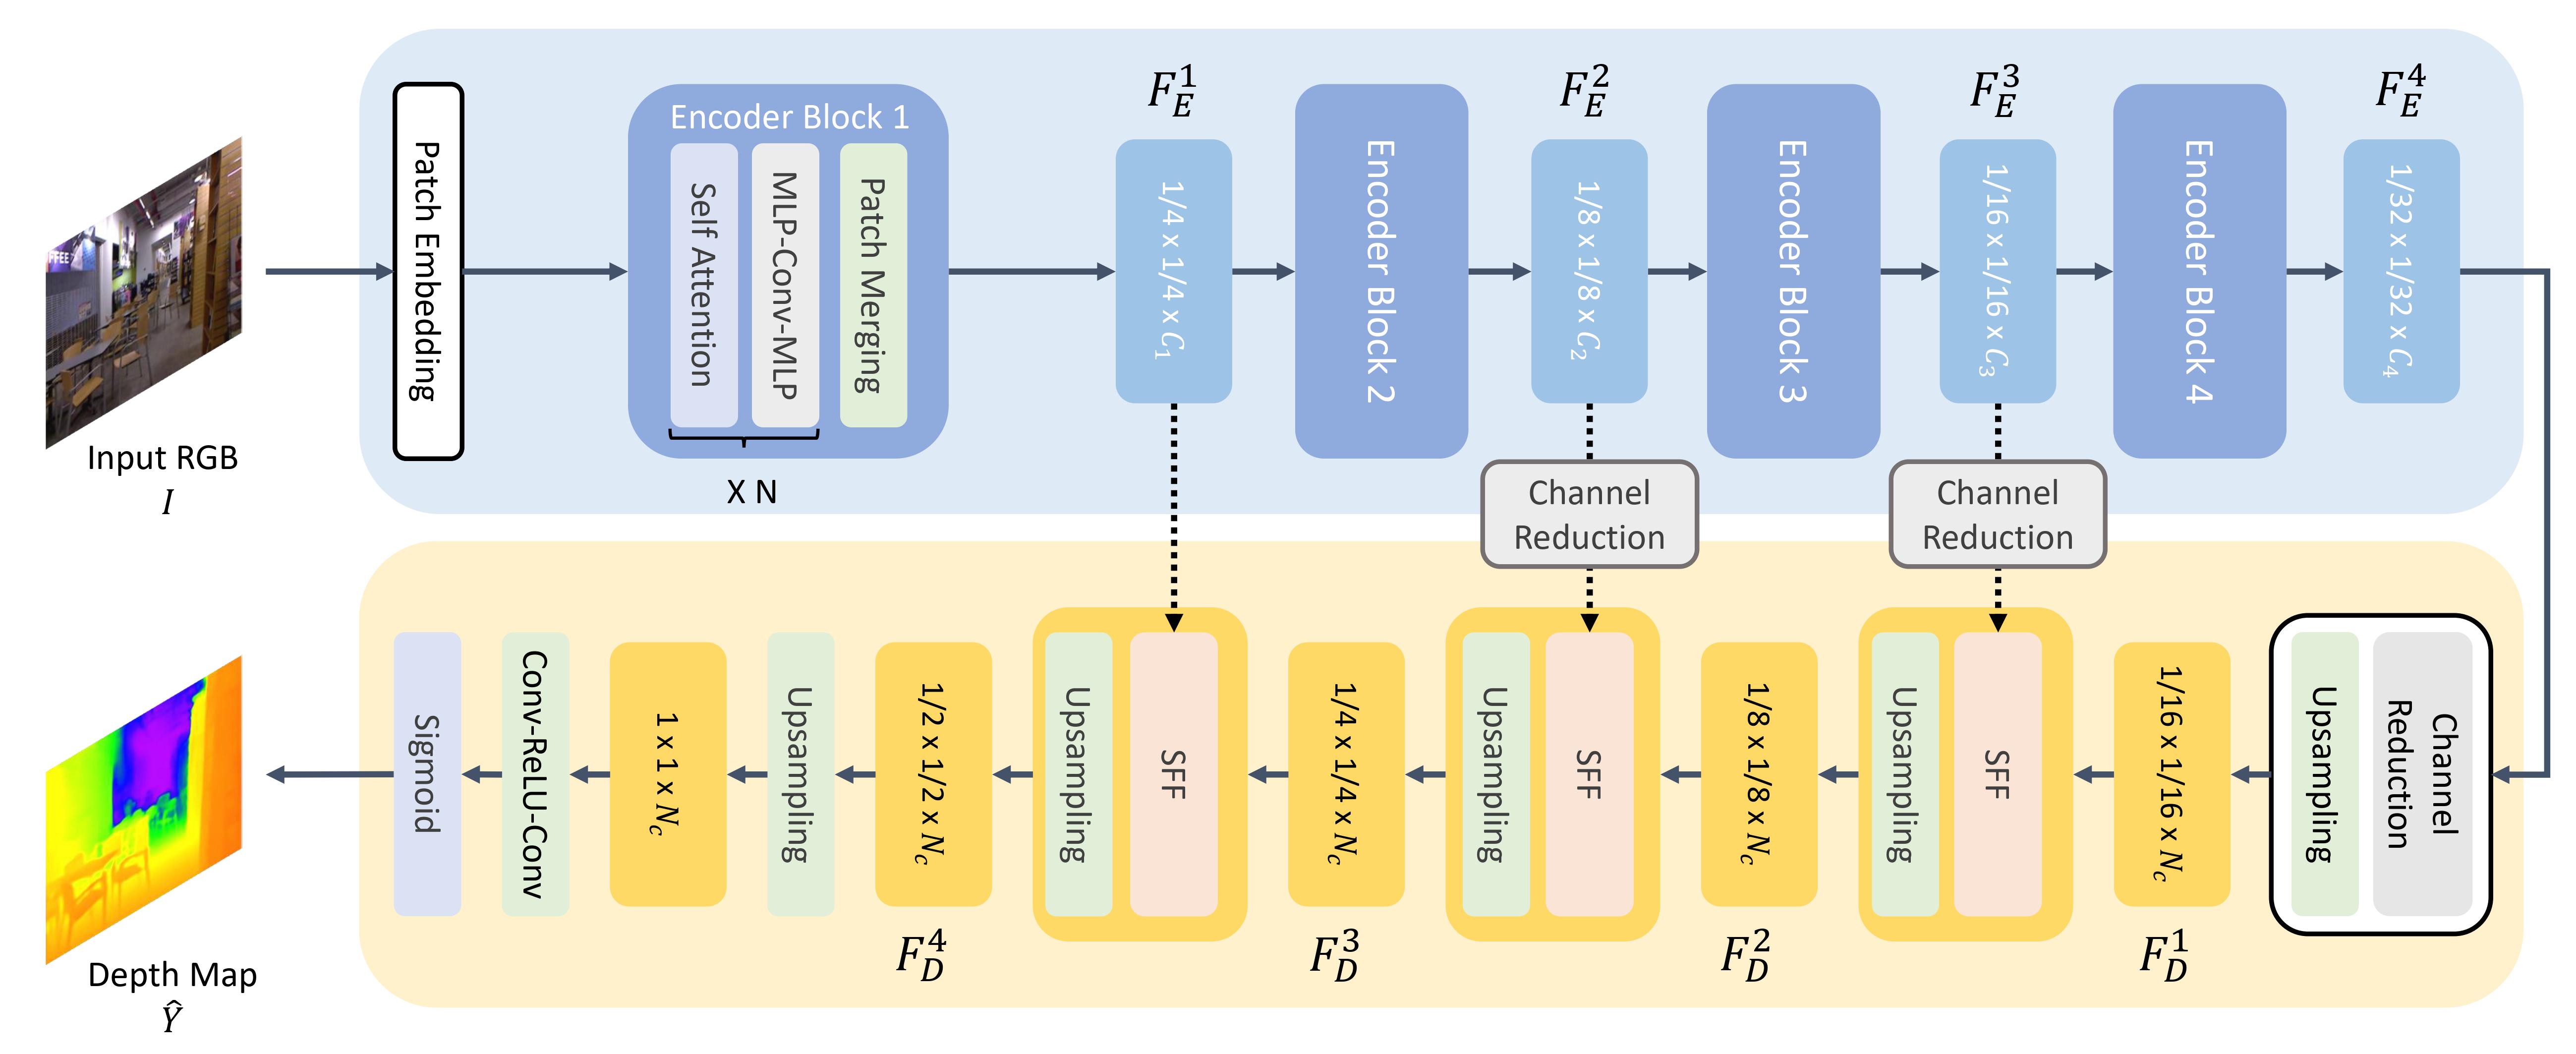 +
+ Summary of the approach. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found [here](https://github.com/vinvino02/GLPDepth).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with GLPN.
+
+- Demo notebooks for [`GLPNForDepthEstimation`] can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/GLPN).
+- [Monocular depth estimation task guide](../tasks/monocular_depth_estimation)
+
+## GLPNConfig
+
+[[autodoc]] GLPNConfig
+
+## GLPNFeatureExtractor
+
+[[autodoc]] GLPNFeatureExtractor
+ - __call__
+
+## GLPNImageProcessor
+
+[[autodoc]] GLPNImageProcessor
+ - preprocess
+
+## GLPNModel
+
+[[autodoc]] GLPNModel
+ - forward
+
+## GLPNForDepthEstimation
+
+[[autodoc]] GLPNForDepthEstimation
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt-sw3.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt-sw3.md
new file mode 100644
index 0000000000000000000000000000000000000000..f69bd958e9c5f1f7ae0e8234215d57fa6002dd80
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/gpt-sw3.md
@@ -0,0 +1,69 @@
+
+
+# GPT-Sw3
+
+## Overview
+
+The GPT-Sw3 model was first proposed in
+[Lessons Learned from GPT-SW3: Building the First Large-Scale Generative Language Model for Swedish](http://www.lrec-conf.org/proceedings/lrec2022/pdf/2022.lrec-1.376.pdf)
+by Ariel Ekgren, Amaru Cuba Gyllensten, Evangelia Gogoulou, Alice Heiman, Severine Verlinden, Joey Öhman,
+Fredrik Carlsson, Magnus Sahlgren.
+
+Since that first paper the authors have extended their work and trained new models on their new 1.2TB corpora named The Nordic Pile.
+
+GPT-Sw3 is a collection of large decoder-only pretrained transformer language models that were developed by AI Sweden
+in collaboration with RISE and the WASP WARA for Media and Language. GPT-Sw3 has been trained on a dataset containing
+320B tokens in Swedish, Norwegian, Danish, Icelandic, English, and programming code. The model was pretrained using a
+causal language modeling (CLM) objective utilizing the NeMo Megatron GPT implementation.
+
+This model was contributed by [AI Sweden Models](https://huggingface.co/AI-Sweden-Models).
+
+## Usage example
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForCausalLM
+
+>>> tokenizer = AutoTokenizer.from_pretrained("AI-Sweden-Models/gpt-sw3-356m")
+>>> model = AutoModelForCausalLM.from_pretrained("AI-Sweden-Models/gpt-sw3-356m")
+
+>>> input_ids = tokenizer("Träd är fina för att", return_tensors="pt")["input_ids"]
+
+>>> generated_token_ids = model.generate(inputs=input_ids, max_new_tokens=10, do_sample=True)[0]
+
+>>> print(tokenizer.decode(generated_token_ids))
+Träd är fina för att de är färgstarka. Men ibland är det fint
+```
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+
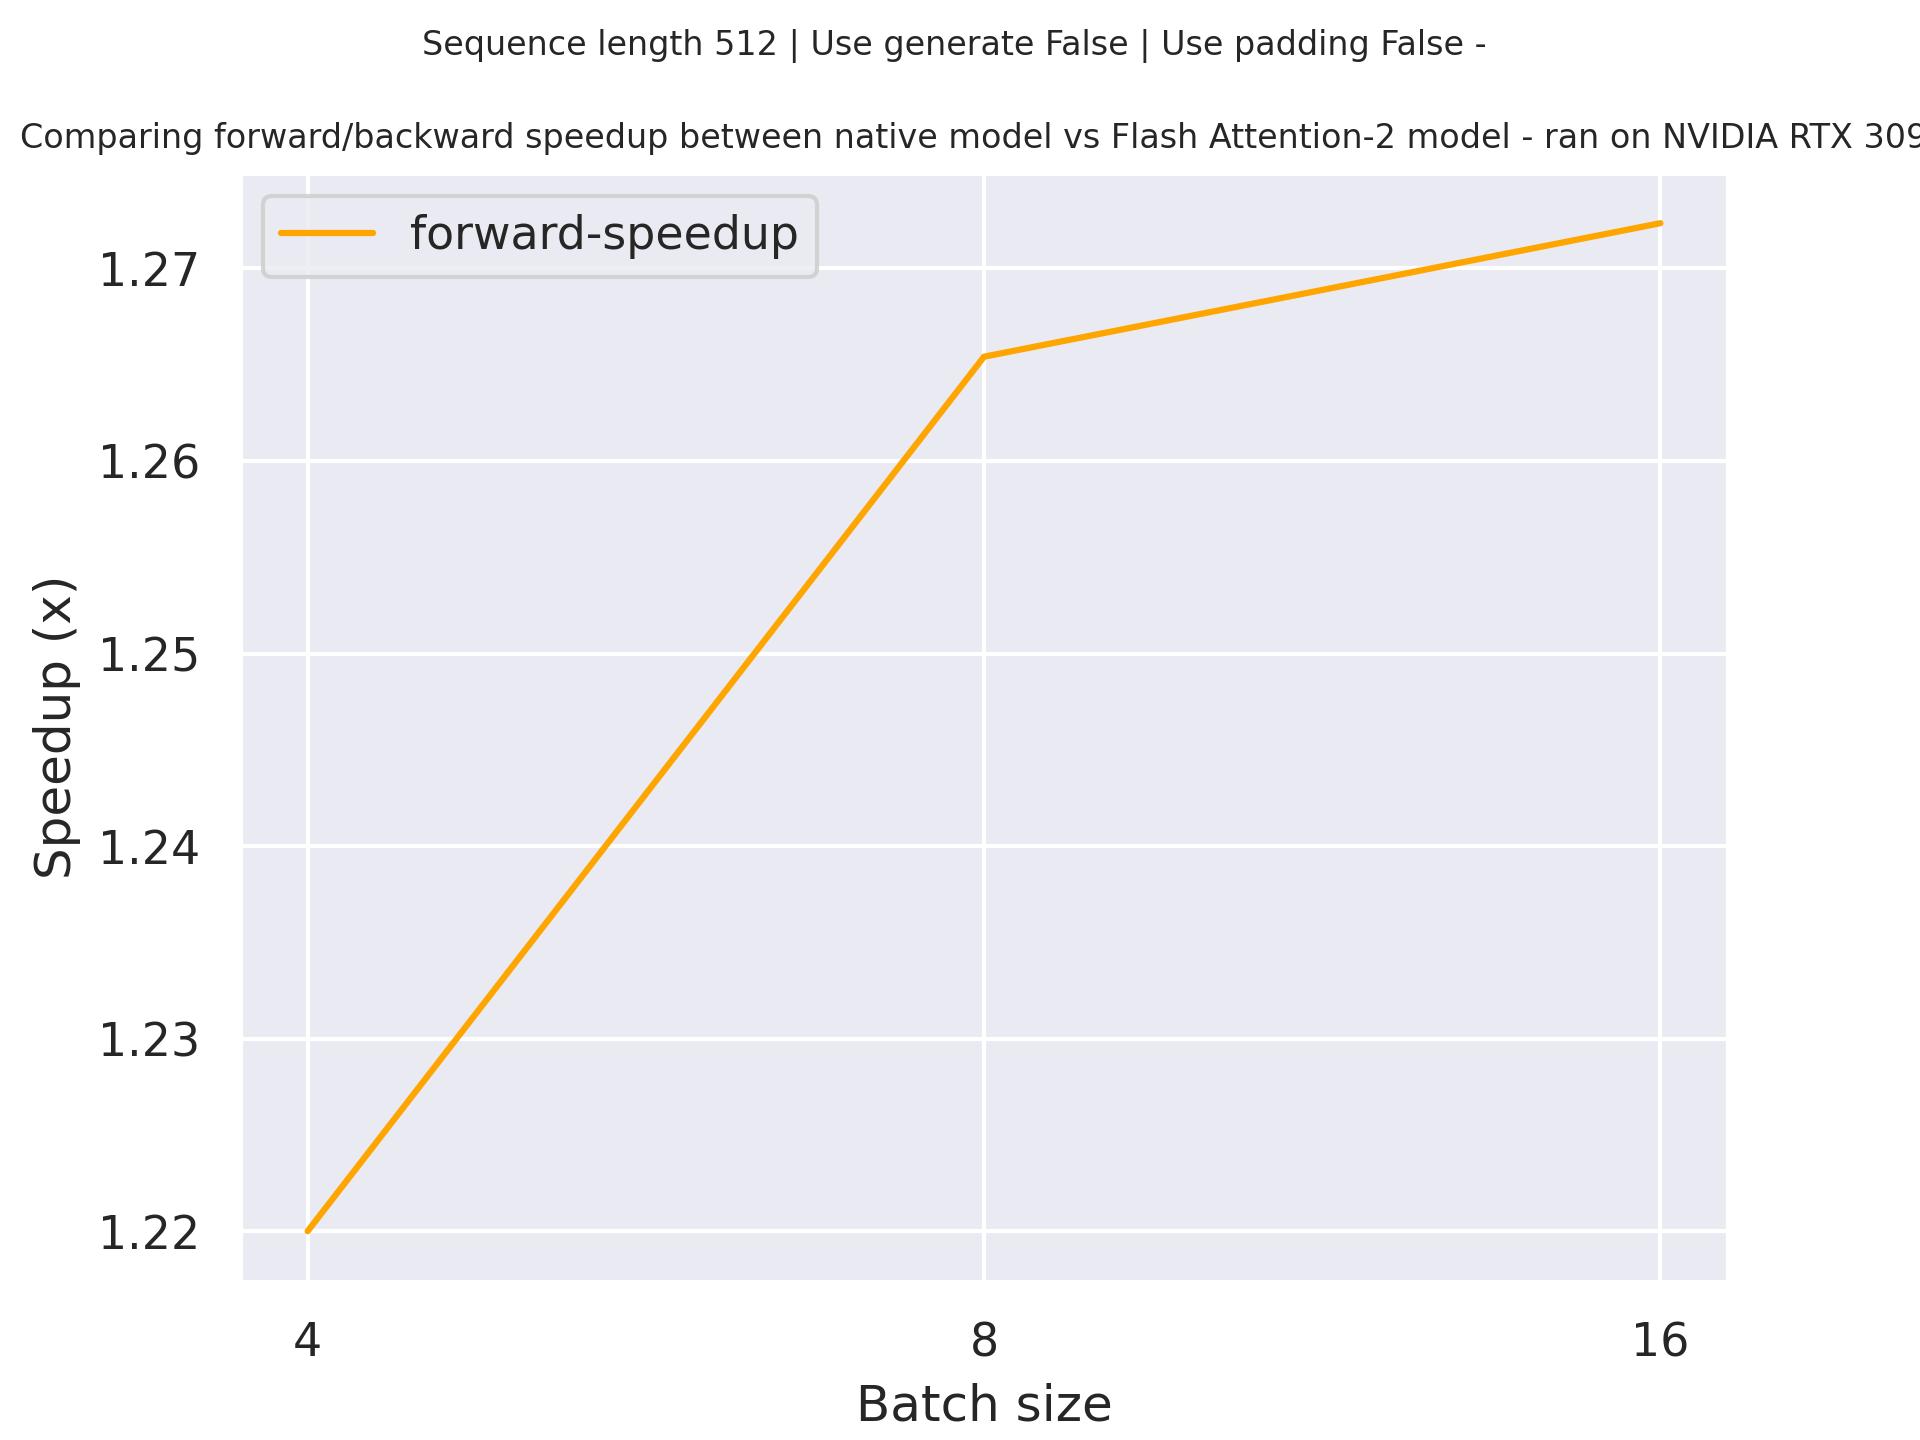 +
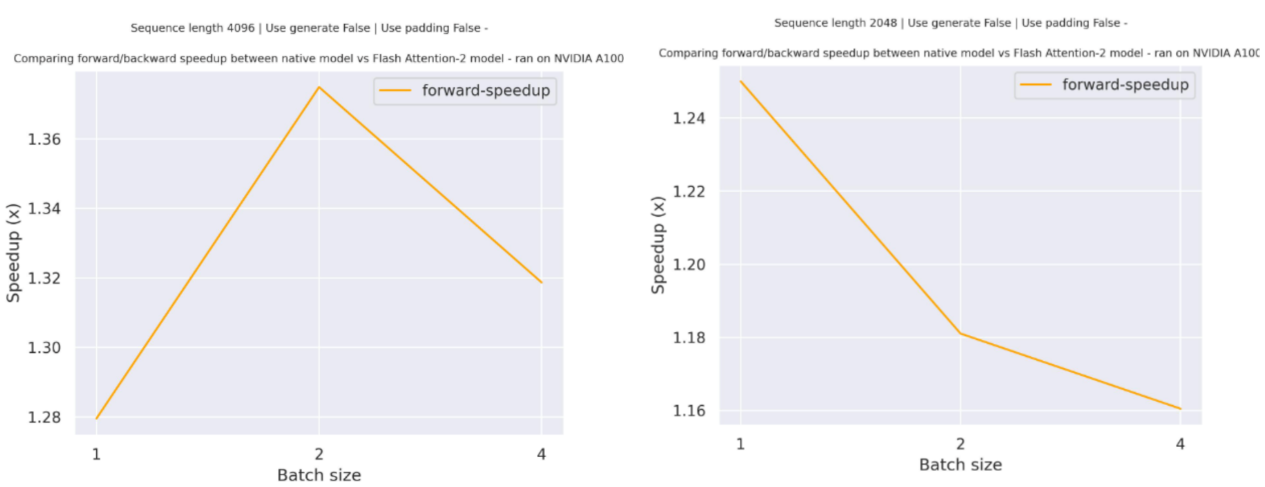 +
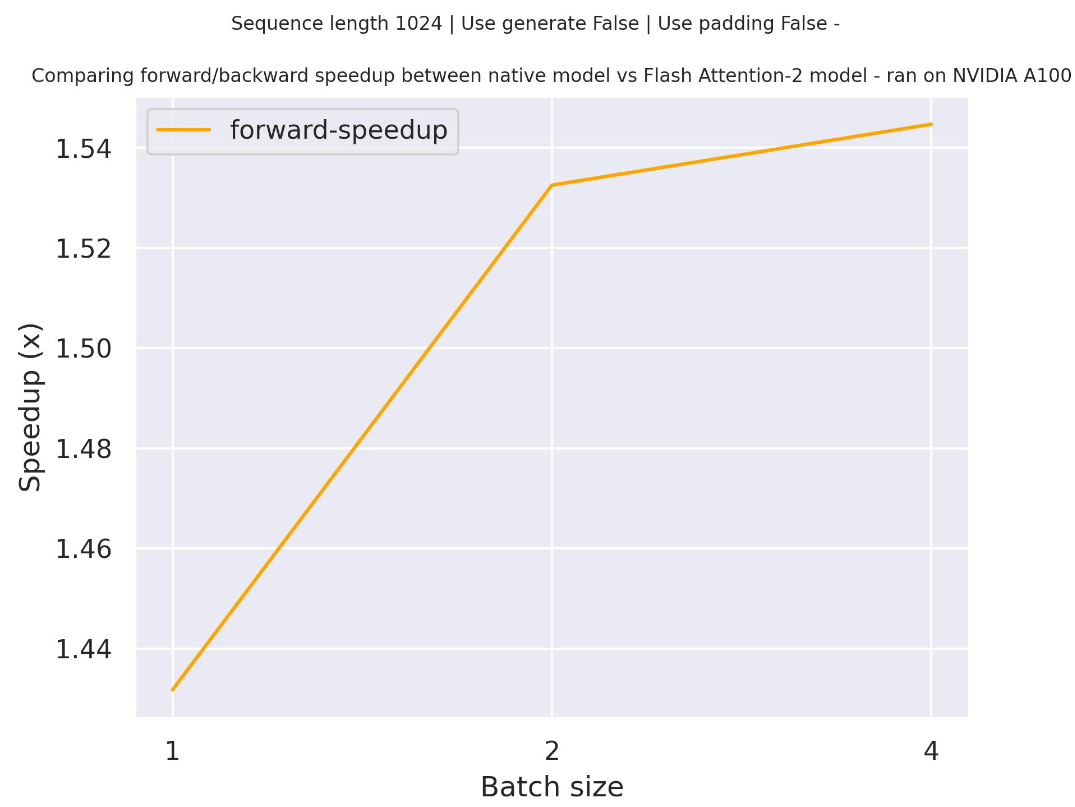 +
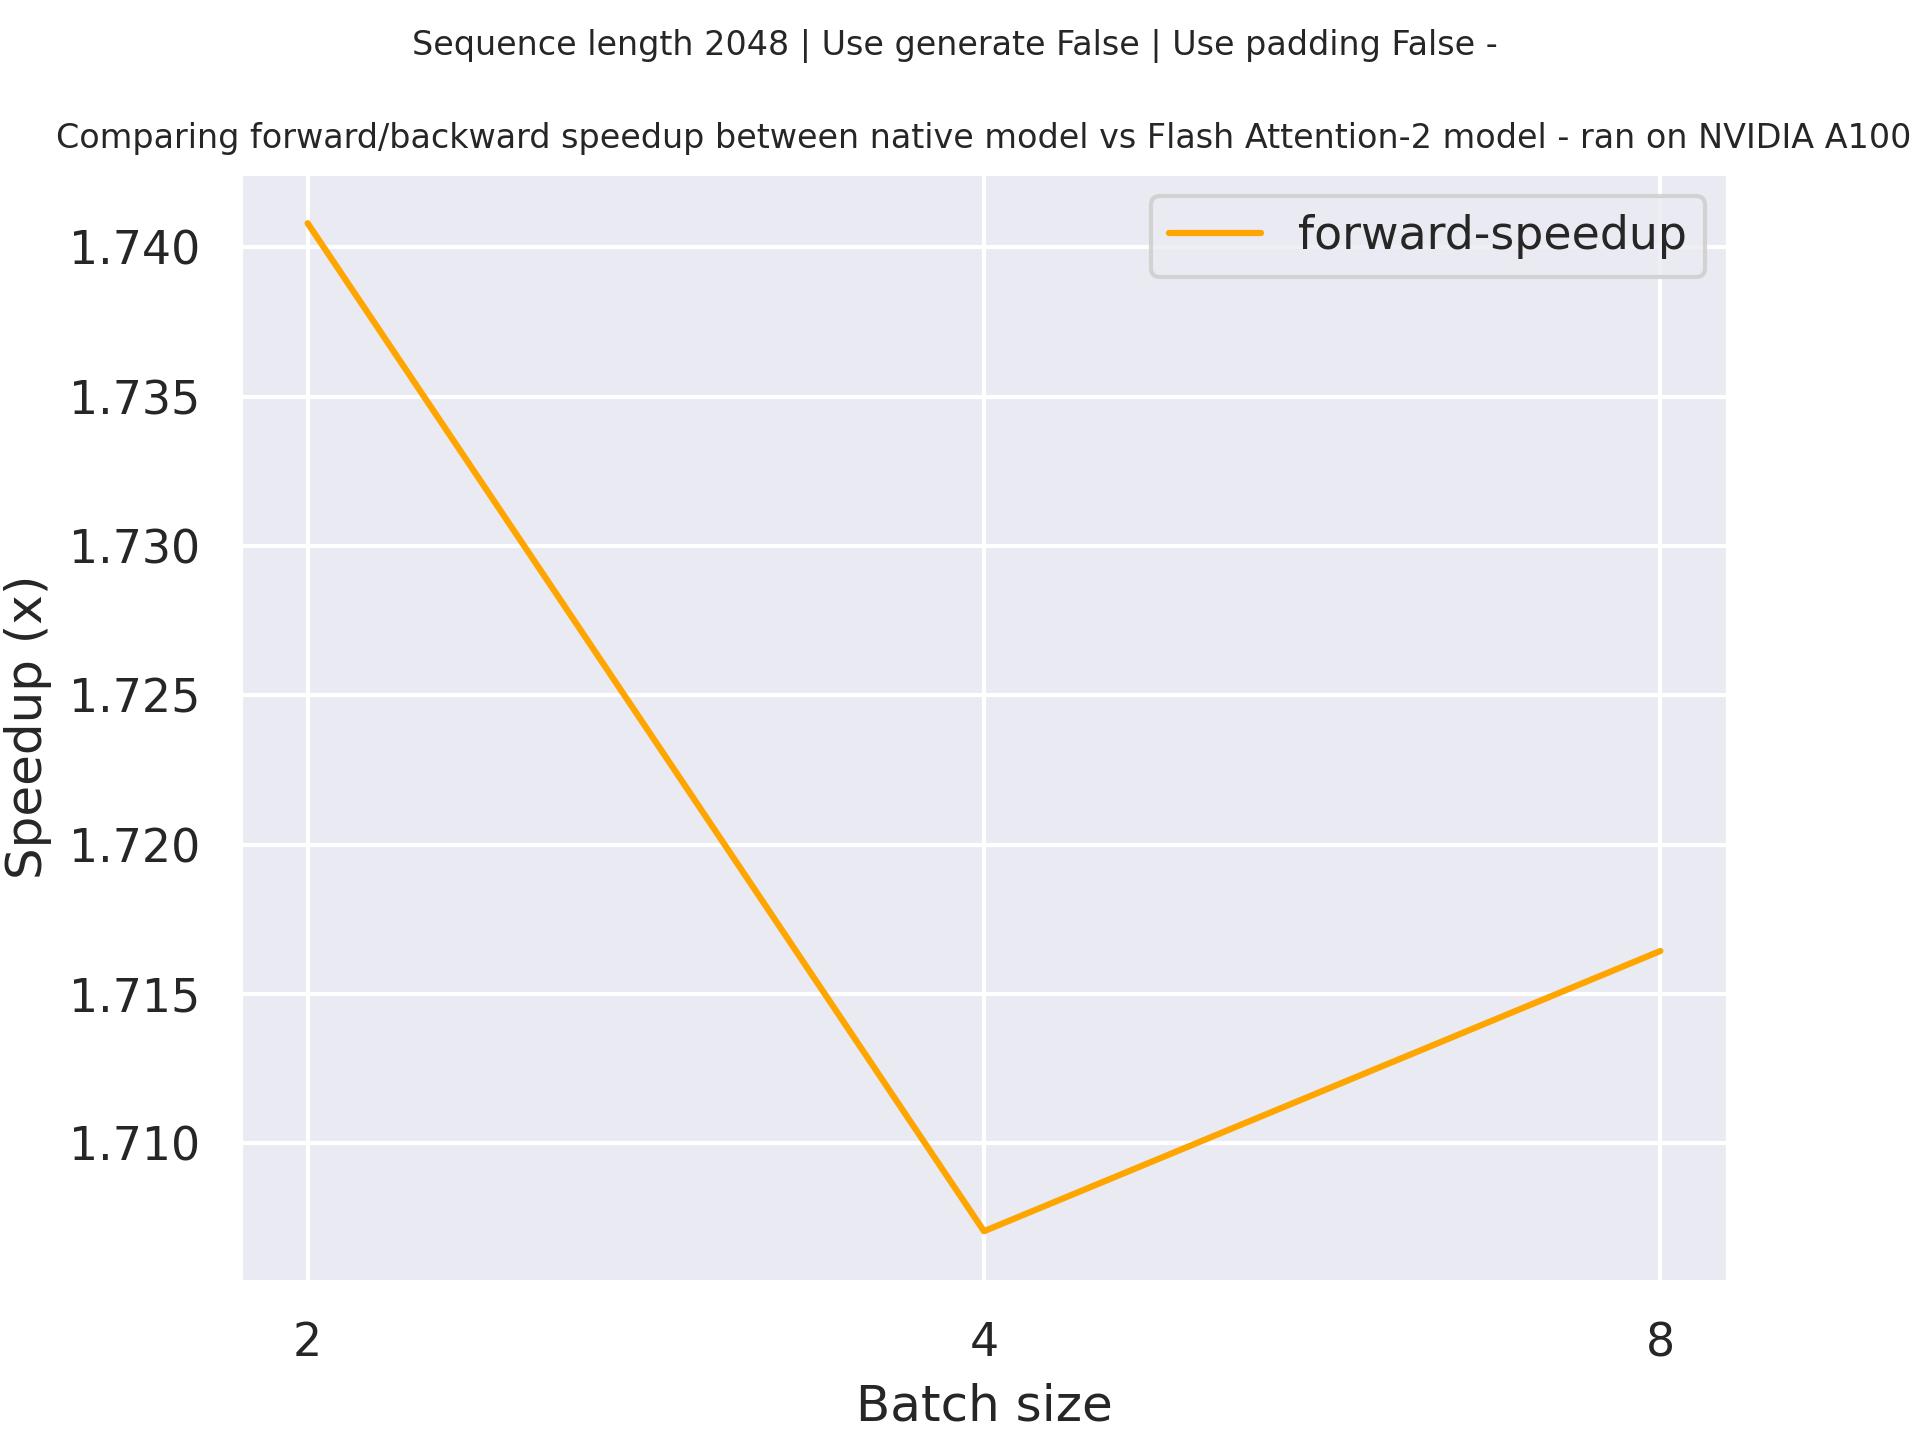 +
 +
+ Grounding DINO overview. Taken from the original paper.
+
+This model was contributed by [EduardoPacheco](https://huggingface.co/EduardoPacheco) and [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/IDEA-Research/GroundingDINO).
+
+## Usage tips
+
+- One can use [`GroundingDinoProcessor`] to prepare image-text pairs for the model.
+- To separate classes in the text use a period e.g. "a cat. a dog."
+- When using multiple classes (e.g. `"a cat. a dog."`), use `post_process_grounded_object_detection` from [`GroundingDinoProcessor`] to post process outputs. Since, the labels returned from `post_process_object_detection` represent the indices from the model dimension where prob > threshold.
+
+Here's how to use the model for zero-shot object detection:
+
+```python
+>>> import requests
+
+>>> import torch
+>>> from PIL import Image
+>>> from transformers import AutoProcessor, AutoModelForZeroShotObjectDetection
+
+>>> model_id = "IDEA-Research/grounding-dino-tiny"
+>>> device = "cuda"
+
+>>> processor = AutoProcessor.from_pretrained(model_id)
+>>> model = AutoModelForZeroShotObjectDetection.from_pretrained(model_id).to(device)
+
+>>> image_url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(image_url, stream=True).raw)
+>>> # Check for cats and remote controls
+>>> text = "a cat. a remote control."
+
+>>> inputs = processor(images=image, text=text, return_tensors="pt").to(device)
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> results = processor.post_process_grounded_object_detection(
+... outputs,
+... inputs.input_ids,
+... box_threshold=0.4,
+... text_threshold=0.3,
+... target_sizes=[image.size[::-1]]
+... )
+>>> print(results)
+[{'boxes': tensor([[344.6959, 23.1090, 637.1833, 374.2751],
+ [ 12.2666, 51.9145, 316.8582, 472.4392],
+ [ 38.5742, 70.0015, 176.7838, 118.1806]], device='cuda:0'),
+ 'labels': ['a cat', 'a cat', 'a remote control'],
+ 'scores': tensor([0.4785, 0.4381, 0.4776], device='cuda:0')}]
+```
+
+## Grounded SAM
+
+One can combine Grounding DINO with the [Segment Anything](sam) model for text-based mask generation as introduced in [Grounded SAM: Assembling Open-World Models for Diverse Visual Tasks](https://arxiv.org/abs/2401.14159). You can refer to this [demo notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/Grounding%20DINO/GroundingDINO_with_Segment_Anything.ipynb) 🌍 for details.
+
+
 +
+ Grounded SAM overview. Taken from the original repository.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Grounding DINO. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- Demo notebooks regarding inference with Grounding DINO as well as combining it with [SAM](sam) can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Grounding%20DINO). 🌎
+
+## GroundingDinoImageProcessor
+
+[[autodoc]] GroundingDinoImageProcessor
+ - preprocess
+ - post_process_object_detection
+
+## GroundingDinoProcessor
+
+[[autodoc]] GroundingDinoProcessor
+ - post_process_grounded_object_detection
+
+## GroundingDinoConfig
+
+[[autodoc]] GroundingDinoConfig
+
+## GroundingDinoModel
+
+[[autodoc]] GroundingDinoModel
+ - forward
+
+## GroundingDinoForObjectDetection
+
+[[autodoc]] GroundingDinoForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/groupvit.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/groupvit.md
new file mode 100644
index 0000000000000000000000000000000000000000..8728cf0da21ba2909abd50fddf48a821707d2f7f
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/groupvit.md
@@ -0,0 +1,96 @@
+
+
+# GroupViT
+
+## Overview
+
+The GroupViT model was proposed in [GroupViT: Semantic Segmentation Emerges from Text Supervision](https://arxiv.org/abs/2202.11094) by Jiarui Xu, Shalini De Mello, Sifei Liu, Wonmin Byeon, Thomas Breuel, Jan Kautz, Xiaolong Wang.
+Inspired by [CLIP](clip), GroupViT is a vision-language model that can perform zero-shot semantic segmentation on any given vocabulary categories.
+
+The abstract from the paper is the following:
+
+*Grouping and recognition are important components of visual scene understanding, e.g., for object detection and semantic segmentation. With end-to-end deep learning systems, grouping of image regions usually happens implicitly via top-down supervision from pixel-level recognition labels. Instead, in this paper, we propose to bring back the grouping mechanism into deep networks, which allows semantic segments to emerge automatically with only text supervision. We propose a hierarchical Grouping Vision Transformer (GroupViT), which goes beyond the regular grid structure representation and learns to group image regions into progressively larger arbitrary-shaped segments. We train GroupViT jointly with a text encoder on a large-scale image-text dataset via contrastive losses. With only text supervision and without any pixel-level annotations, GroupViT learns to group together semantic regions and successfully transfers to the task of semantic segmentation in a zero-shot manner, i.e., without any further fine-tuning. It achieves a zero-shot accuracy of 52.3% mIoU on the PASCAL VOC 2012 and 22.4% mIoU on PASCAL Context datasets, and performs competitively to state-of-the-art transfer-learning methods requiring greater levels of supervision.*
+
+This model was contributed by [xvjiarui](https://huggingface.co/xvjiarui). The TensorFlow version was contributed by [ariG23498](https://huggingface.co/ariG23498) with the help of [Yih-Dar SHIEH](https://huggingface.co/ydshieh), [Amy Roberts](https://huggingface.co/amyeroberts), and [Joao Gante](https://huggingface.co/joaogante).
+The original code can be found [here](https://github.com/NVlabs/GroupViT).
+
+## Usage tips
+
+- You may specify `output_segmentation=True` in the forward of `GroupViTModel` to get the segmentation logits of input texts.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with GroupViT.
+
+- The quickest way to get started with GroupViT is by checking the [example notebooks](https://github.com/xvjiarui/GroupViT/blob/main/demo/GroupViT_hf_inference_notebook.ipynb) (which showcase zero-shot segmentation inference).
+- One can also check out the [HuggingFace Spaces demo](https://huggingface.co/spaces/xvjiarui/GroupViT) to play with GroupViT.
+
+## GroupViTConfig
+
+[[autodoc]] GroupViTConfig
+ - from_text_vision_configs
+
+## GroupViTTextConfig
+
+[[autodoc]] GroupViTTextConfig
+
+## GroupViTVisionConfig
+
+[[autodoc]] GroupViTVisionConfig
+
+
 +
+ Hiera architecture. Taken from the original paper.
+
+This model was a joint contribution by [EduardoPacheco](https://huggingface.co/EduardoPacheco) and [namangarg110](https://huggingface.co/namangarg110). The original code can be found [here] (https://github.com/facebookresearch/hiera).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Hiera. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
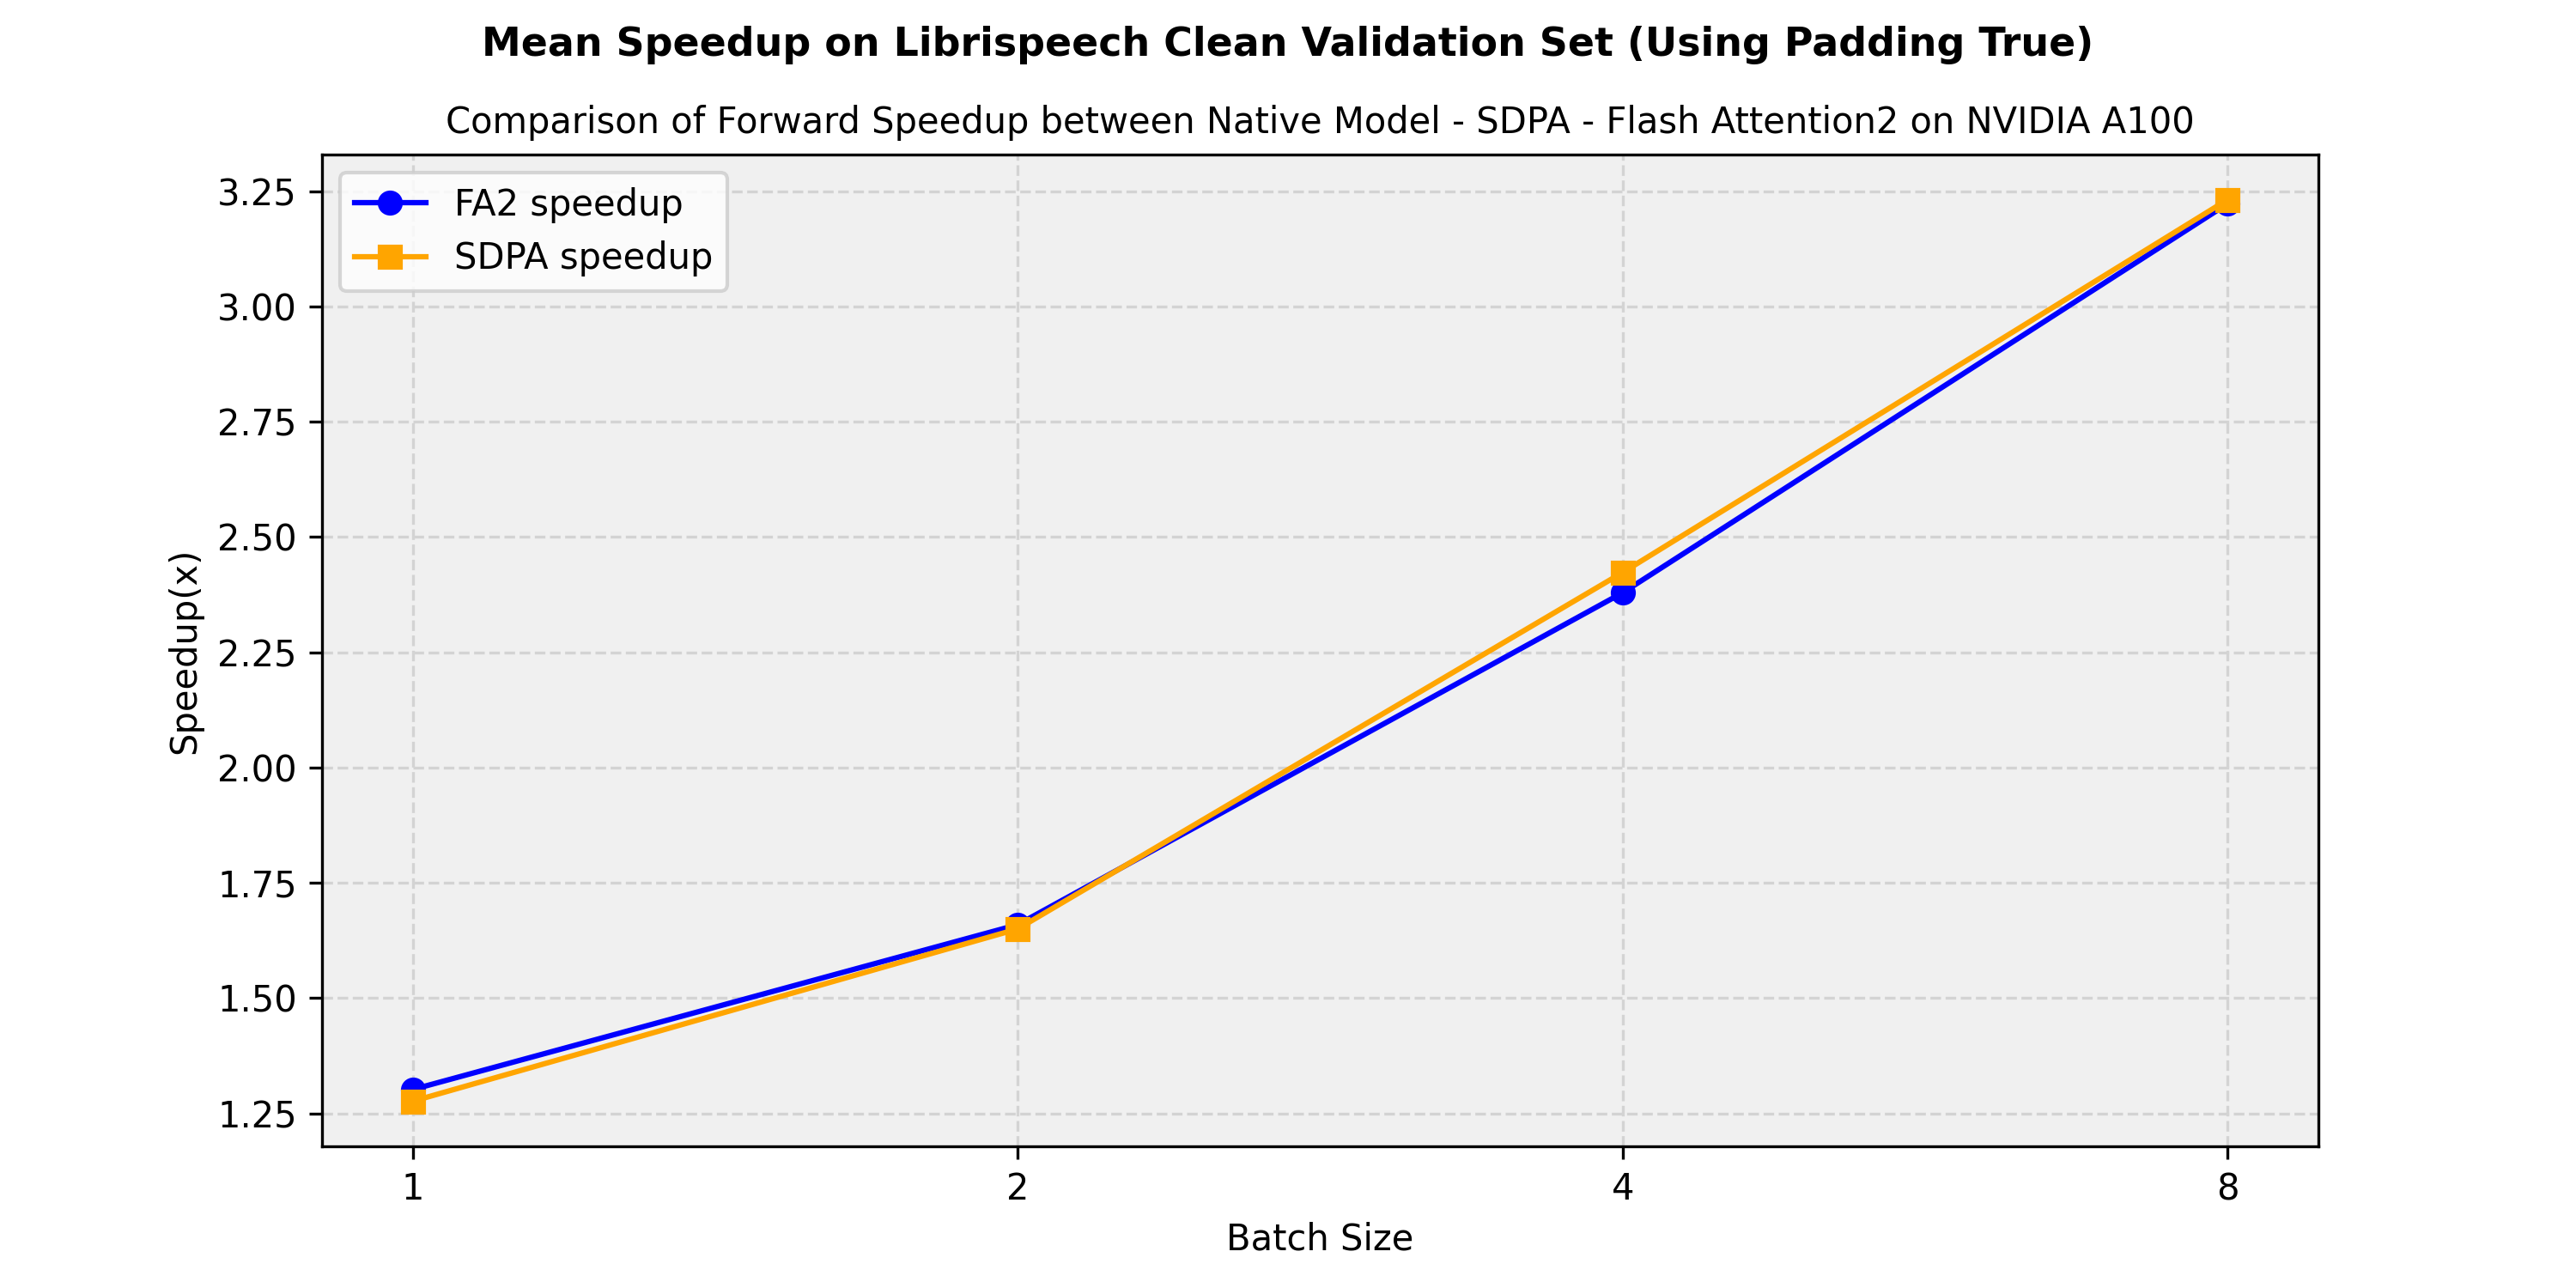 +
 +
+ Idefics2 architecture. Taken from the original paper.
+
+This model was contributed by [amyeroberts](https://huggingface.co/amyeroberts).
+The original code can be found [here](https://huggingface.co/HuggingFaceM4/idefics2).
+
+## Usage tips
+
+- Each sample can contain multiple images, and the number of images can vary between samples. The processor will pad the inputs to the maximum number of images in a batch for input to the model.
+- The processor has a `do_image_splitting` option. If `True`, each input image will be split into 4 sub-images, and concatenated with the original to form 5 images. This is useful for increasing model performance. Make sure `processor.image_processor.do_image_splitting` is set to `False` if the model was not trained with this option.
+- `text` passed to the processor should have the `
 +
+ I-JEPA architecture. Taken from the original paper.
+
+This model was contributed by [jmtzt](https://huggingface.co/jmtzt).
+The original code can be found [here](https://github.com/facebookresearch/ijepa).
+
+## How to use
+
+Here is how to use this model for image feature extraction:
+
+```python
+import requests
+import torch
+from PIL import Image
+from torch.nn.functional import cosine_similarity
+
+from transformers import AutoModel, AutoProcessor
+
+url_1 = "http://images.cocodataset.org/val2017/000000039769.jpg"
+url_2 = "http://images.cocodataset.org/val2017/000000219578.jpg"
+image_1 = Image.open(requests.get(url_1, stream=True).raw)
+image_2 = Image.open(requests.get(url_2, stream=True).raw)
+
+model_id = "facebook/ijepa_vith14_1k"
+processor = AutoProcessor.from_pretrained(model_id)
+model = AutoModel.from_pretrained(model_id)
+
+@torch.no_grad()
+def infer(image):
+ inputs = processor(image, return_tensors="pt")
+ outputs = model(**inputs)
+ return outputs.last_hidden_state.mean(dim=1)
+
+
+embed_1 = infer(image_1)
+embed_2 = infer(image_2)
+
+similarity = cosine_similarity(embed_1, embed_2)
+print(similarity)
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with I-JEPA.
+
+
 +
+ Summary of the approach. Taken from the [original paper](https://cdn.openai.com/papers/Generative_Pretraining_from_Pixels_V2.pdf).
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr), based on [this issue](https://github.com/openai/image-gpt/issues/7). The original code can be found
+[here](https://github.com/openai/image-gpt).
+
+## Usage tips
+
+- ImageGPT is almost exactly the same as [GPT-2](gpt2), with the exception that a different activation
+ function is used (namely "quick gelu"), and the layer normalization layers don't mean center the inputs. ImageGPT
+ also doesn't have tied input- and output embeddings.
+- As the time- and memory requirements of the attention mechanism of Transformers scales quadratically in the sequence
+ length, the authors pre-trained ImageGPT on smaller input resolutions, such as 32x32 and 64x64. However, feeding a
+ sequence of 32x32x3=3072 tokens from 0..255 into a Transformer is still prohibitively large. Therefore, the authors
+ applied k-means clustering to the (R,G,B) pixel values with k=512. This way, we only have a 32*32 = 1024-long
+ sequence, but now of integers in the range 0..511. So we are shrinking the sequence length at the cost of a bigger
+ embedding matrix. In other words, the vocabulary size of ImageGPT is 512, + 1 for a special "start of sentence" (SOS)
+ token, used at the beginning of every sequence. One can use [`ImageGPTImageProcessor`] to prepare
+ images for the model.
+- Despite being pre-trained entirely unsupervised (i.e. without the use of any labels), ImageGPT produces fairly
+ performant image features useful for downstream tasks, such as image classification. The authors showed that the
+ features in the middle of the network are the most performant, and can be used as-is to train a linear model (such as
+ a sklearn logistic regression model for example). This is also referred to as "linear probing". Features can be
+ easily obtained by first forwarding the image through the model, then specifying `output_hidden_states=True`, and
+ then average-pool the hidden states at whatever layer you like.
+- Alternatively, one can further fine-tune the entire model on a downstream dataset, similar to BERT. For this, you can
+ use [`ImageGPTForImageClassification`].
+- ImageGPT comes in different sizes: there's ImageGPT-small, ImageGPT-medium and ImageGPT-large. The authors did also
+ train an XL variant, which they didn't release. The differences in size are summarized in the following table:
+
+| **Model variant** | **Depths** | **Hidden sizes** | **Decoder hidden size** | **Params (M)** | **ImageNet-1k Top 1** |
+|---|---|---|---|---|---|
+| MiT-b0 | [2, 2, 2, 2] | [32, 64, 160, 256] | 256 | 3.7 | 70.5 |
+| MiT-b1 | [2, 2, 2, 2] | [64, 128, 320, 512] | 256 | 14.0 | 78.7 |
+| MiT-b2 | [3, 4, 6, 3] | [64, 128, 320, 512] | 768 | 25.4 | 81.6 |
+| MiT-b3 | [3, 4, 18, 3] | [64, 128, 320, 512] | 768 | 45.2 | 83.1 |
+| MiT-b4 | [3, 8, 27, 3] | [64, 128, 320, 512] | 768 | 62.6 | 83.6 |
+| MiT-b5 | [3, 6, 40, 3] | [64, 128, 320, 512] | 768 | 82.0 | 83.8 |
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with ImageGPT.
+
+
 +
+ InstructBLIP architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/salesforce/LAVIS/tree/main/projects/instructblip).
+
+## Usage tips
+
+InstructBLIP uses the same architecture as [BLIP-2](blip2) with a tiny but important difference: it also feeds the text prompt (instruction) to the Q-Former.
+
+> [!NOTE]
+> BLIP models after release v4.46 will raise warnings about adding `processor.num_query_tokens = {{num_query_tokens}}` and expand model embeddings layer to add special `
 +
+## Usage
+
+### Prerequisites
+
+Jamba requires you use `transformers` version 4.39.0 or higher:
+```bash
+pip install transformers>=4.39.0
+```
+
+In order to run optimized Mamba implementations, you first need to install `mamba-ssm` and `causal-conv1d`:
+```bash
+pip install mamba-ssm causal-conv1d>=1.2.0
+```
+You also have to have the model on a CUDA device.
+
+You can run the model not using the optimized Mamba kernels, but it is **not** recommended as it will result in significantly lower latencies. In order to do that, you'll need to specify `use_mamba_kernels=False` when loading the model.
+
+### Run the model
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained("ai21labs/Jamba-v0.1")
+tokenizer = AutoTokenizer.from_pretrained("ai21labs/Jamba-v0.1")
+
+input_ids = tokenizer("In the recent Super Bowl LVIII,", return_tensors='pt').to(model.device)["input_ids"]
+
+outputs = model.generate(input_ids, max_new_tokens=216)
+
+print(tokenizer.batch_decode(outputs))
+# ["<|startoftext|>In the recent Super Bowl LVIII, the Kansas City Chiefs emerged victorious, defeating the San Francisco 49ers in a thrilling overtime showdown. The game was a nail-biter, with both teams showcasing their skills and determination.\n\nThe Chiefs, led by their star quarterback Patrick Mahomes, displayed their offensive prowess, while the 49ers, led by their strong defense, put up a tough fight. The game went into overtime, with the Chiefs ultimately securing the win with a touchdown.\n\nThe victory marked the Chiefs' second Super Bowl win in four years, solidifying their status as one of the top teams in the NFL. The game was a testament to the skill and talent of both teams, and a thrilling end to the NFL season.\n\nThe Super Bowl is not just about the game itself, but also about the halftime show and the commercials. This year's halftime show featured a star-studded lineup, including Usher, Alicia Keys, and Lil Jon. The show was a spectacle of music and dance, with the performers delivering an energetic and entertaining performance.\n"]
+```
+
+
 +
+ Overview of tasks that KOSMOS-2 can handle. Taken from the original paper.
+
+## Example
+
+```python
+>>> from PIL import Image
+>>> import requests
+>>> from transformers import AutoProcessor, Kosmos2ForConditionalGeneration
+
+>>> model = Kosmos2ForConditionalGeneration.from_pretrained("microsoft/kosmos-2-patch14-224")
+>>> processor = AutoProcessor.from_pretrained("microsoft/kosmos-2-patch14-224")
+
+>>> url = "https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/snowman.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> prompt = "
 +
+ LayoutLMv3 architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The TensorFlow version of this model was added by [chriskoo](https://huggingface.co/chriskoo), [tokec](https://huggingface.co/tokec), and [lre](https://huggingface.co/lre). The original code can be found [here](https://github.com/microsoft/unilm/tree/master/layoutlmv3).
+
+## Usage tips
+
+- In terms of data processing, LayoutLMv3 is identical to its predecessor [LayoutLMv2](layoutlmv2), except that:
+ - images need to be resized and normalized with channels in regular RGB format. LayoutLMv2 on the other hand normalizes the images internally and expects the channels in BGR format.
+ - text is tokenized using byte-pair encoding (BPE), as opposed to WordPiece.
+ Due to these differences in data preprocessing, one can use [`LayoutLMv3Processor`] which internally combines a [`LayoutLMv3ImageProcessor`] (for the image modality) and a [`LayoutLMv3Tokenizer`]/[`LayoutLMv3TokenizerFast`] (for the text modality) to prepare all data for the model.
+- Regarding usage of [`LayoutLMv3Processor`], we refer to the [usage guide](layoutlmv2#usage-layoutlmv2processor) of its predecessor.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LayoutLMv3. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
 +
+ LeViT Architecture. Taken from the original paper.
+
+This model was contributed by [anugunj](https://huggingface.co/anugunj). The original code can be found [here](https://github.com/facebookresearch/LeViT).
+
+## Usage tips
+
+- Compared to ViT, LeViT models use an additional distillation head to effectively learn from a teacher (which, in the LeViT paper, is a ResNet like-model). The distillation head is learned through backpropagation under supervision of a ResNet like-model. They also draw inspiration from convolution neural networks to use activation maps with decreasing resolutions to increase the efficiency.
+- There are 2 ways to fine-tune distilled models, either (1) in a classic way, by only placing a prediction head on top
+ of the final hidden state and not using the distillation head, or (2) by placing both a prediction head and distillation
+ head on top of the final hidden state. In that case, the prediction head is trained using regular cross-entropy between
+ the prediction of the head and the ground-truth label, while the distillation prediction head is trained using hard distillation
+ (cross-entropy between the prediction of the distillation head and the label predicted by the teacher). At inference time,
+ one takes the average prediction between both heads as final prediction. (2) is also called "fine-tuning with distillation",
+ because one relies on a teacher that has already been fine-tuned on the downstream dataset. In terms of models, (1) corresponds
+ to [`LevitForImageClassification`] and (2) corresponds to [`LevitForImageClassificationWithTeacher`].
+- All released checkpoints were pre-trained and fine-tuned on [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k)
+ (also referred to as ILSVRC 2012, a collection of 1.3 million images and 1,000 classes). only. No external data was used. This is in
+ contrast with the original ViT model, which used external data like the JFT-300M dataset/Imagenet-21k for
+ pre-training.
+- The authors of LeViT released 5 trained LeViT models, which you can directly plug into [`LevitModel`] or [`LevitForImageClassification`].
+ Techniques like data augmentation, optimization, and regularization were used in order to simulate training on a much larger dataset
+ (while only using ImageNet-1k for pre-training). The 5 variants available are (all trained on images of size 224x224):
+ *facebook/levit-128S*, *facebook/levit-128*, *facebook/levit-192*, *facebook/levit-256* and
+ *facebook/levit-384*. Note that one should use [`LevitImageProcessor`] in order to
+ prepare images for the model.
+- [`LevitForImageClassificationWithTeacher`] currently supports only inference and not training or fine-tuning.
+- You can check out demo notebooks regarding inference as well as fine-tuning on custom data [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/VisionTransformer)
+ (you can just replace [`ViTFeatureExtractor`] by [`LevitImageProcessor`] and [`ViTForImageClassification`] by [`LevitForImageClassification`] or [`LevitForImageClassificationWithTeacher`]).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LeViT.
+
+
 +
+ LiLT architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/jpwang/lilt).
+
+## Usage tips
+
+- To combine the Language-Independent Layout Transformer with a new RoBERTa checkpoint from the [hub](https://huggingface.co/models?search=roberta), refer to [this guide](https://github.com/jpWang/LiLT#or-generate-your-own-checkpoint-optional).
+The script will result in `config.json` and `pytorch_model.bin` files being stored locally. After doing this, one can do the following (assuming you're logged in with your HuggingFace account):
+
+```python
+from transformers import LiltModel
+
+model = LiltModel.from_pretrained("path_to_your_files")
+model.push_to_hub("name_of_repo_on_the_hub")
+```
+
+- When preparing data for the model, make sure to use the token vocabulary that corresponds to the RoBERTa checkpoint you combined with the Layout Transformer.
+- As [lilt-roberta-en-base](https://huggingface.co/SCUT-DLVCLab/lilt-roberta-en-base) uses the same vocabulary as [LayoutLMv3](layoutlmv3), one can use [`LayoutLMv3TokenizerFast`] to prepare data for the model.
+The same is true for [lilt-roberta-en-base](https://huggingface.co/SCUT-DLVCLab/lilt-infoxlm-base): one can use [`LayoutXLMTokenizerFast`] for that model.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LiLT.
+
+- Demo notebooks for LiLT can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/LiLT).
+
+**Documentation resources**
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## LiltConfig
+
+[[autodoc]] LiltConfig
+
+## LiltModel
+
+[[autodoc]] LiltModel
+ - forward
+
+## LiltForSequenceClassification
+
+[[autodoc]] LiltForSequenceClassification
+ - forward
+
+## LiltForTokenClassification
+
+[[autodoc]] LiltForTokenClassification
+ - forward
+
+## LiltForQuestionAnswering
+
+[[autodoc]] LiltForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llama.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llama.md
new file mode 100644
index 0000000000000000000000000000000000000000..2f0eb63da00a84278d4da782e09a84620d58c963
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/llama.md
@@ -0,0 +1,137 @@
+
+
+# LLaMA
+
+## Overview
+
+The LLaMA model was proposed in [LLaMA: Open and Efficient Foundation Language Models](https://arxiv.org/abs/2302.13971) by Hugo Touvron, Thibaut Lavril, Gautier Izacard, Xavier Martinet, Marie-Anne Lachaux, Timothée Lacroix, Baptiste Rozière, Naman Goyal, Eric Hambro, Faisal Azhar, Aurelien Rodriguez, Armand Joulin, Edouard Grave, Guillaume Lample. It is a collection of foundation language models ranging from 7B to 65B parameters.
+
+The abstract from the paper is the following:
+
+*We introduce LLaMA, a collection of foundation language models ranging from 7B to 65B parameters. We train our models on trillions of tokens, and show that it is possible to train state-of-the-art models using publicly available datasets exclusively, without resorting to proprietary and inaccessible datasets. In particular, LLaMA-13B outperforms GPT-3 (175B) on most benchmarks, and LLaMA-65B is competitive with the best models, Chinchilla-70B and PaLM-540B. We release all our models to the research community. *
+
+This model was contributed by [zphang](https://huggingface.co/zphang) with contributions from [BlackSamorez](https://huggingface.co/BlackSamorez). The code of the implementation in Hugging Face is based on GPT-NeoX [here](https://github.com/EleutherAI/gpt-neox). The original code of the authors can be found [here](https://github.com/facebookresearch/llama).
+
+## Usage tips
+
+- Weights for the LLaMA models can be obtained from by filling out [this form](https://docs.google.com/forms/d/e/1FAIpQLSfqNECQnMkycAp2jP4Z9TFX0cGR4uf7b_fBxjY_OjhJILlKGA/viewform?usp=send_form)
+- After downloading the weights, they will need to be converted to the Hugging Face Transformers format using the [conversion script](https://github.com/huggingface/transformers/blob/main/src/transformers/models/llama/convert_llama_weights_to_hf.py). The script can be called with the following (example) command:
+
+```bash
+python src/transformers/models/llama/convert_llama_weights_to_hf.py \
+ --input_dir /path/to/downloaded/llama/weights --model_size 7B --output_dir /output/path
+```
+
+- After conversion, the model and tokenizer can be loaded via:
+
+```python
+from transformers import LlamaForCausalLM, LlamaTokenizer
+
+tokenizer = LlamaTokenizer.from_pretrained("/output/path")
+model = LlamaForCausalLM.from_pretrained("/output/path")
+```
+
+Note that executing the script requires enough CPU RAM to host the whole model in float16 precision (even if the biggest versions
+come in several checkpoints they each contain a part of each weight of the model, so we need to load them all in RAM). For the 65B model, it's thus 130GB of RAM needed.
+
+- The LLaMA tokenizer is a BPE model based on [sentencepiece](https://github.com/google/sentencepiece). One quirk of sentencepiece is that when decoding a sequence, if the first token is the start of the word (e.g. "Banana"), the tokenizer does not prepend the prefix space to the string.
+
+This model was contributed by [zphang](https://huggingface.co/zphang) with contributions from [BlackSamorez](https://huggingface.co/BlackSamorez). The code of the implementation in Hugging Face is based on GPT-NeoX [here](https://github.com/EleutherAI/gpt-neox). The original code of the authors can be found [here](https://github.com/facebookresearch/llama). The Flax version of the implementation was contributed by [afmck](https://huggingface.co/afmck) with the code in the implementation based on Hugging Face's Flax GPT-Neo.
+
+
+Based on the original LLaMA model, Meta AI has released some follow-up works:
+
+- **Llama2**: Llama2 is an improved version of Llama with some architectural tweaks (Grouped Query Attention), and is pre-trained on 2Trillion tokens. Refer to the documentation of Llama2 which can be found [here](llama2).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LLaMA. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
 +
+ LLaVa architecture. Taken from the original paper.
+
+This model was contributed by [ArthurZ](https://huggingface.co/ArthurZ) and [ybelkada](https://huggingface.co/ybelkada).
+The original code can be found [here](https://github.com/haotian-liu/LLaVA/tree/main/llava).
+
+## Usage tips
+
+- We advise users to use `padding_side="left"` when computing batched generation as it leads to more accurate results. Simply make sure to call `processor.tokenizer.padding_side = "left"` before generating.
+
+- Note the model has not been explicitly trained to process multiple images in the same prompt, although this is technically possible, you may experience inaccurate results.
+
+
+> [!NOTE]
+> LLaVA models after release v4.46 will raise warnings about adding `processor.patch_size = {{patch_size}}`, `processor.num_additional_image_tokens = {{num_additional_image_tokens}}` and processor.vision_feature_select_strategy = {{vision_feature_select_strategy}}`. It is strongly recommended to add the attributes to the processor if you own the model checkpoint, or open a PR if it is not owned by you.
+Adding these attributes means that LLaVA will try to infer the number of image tokens required per image and expand the text with as many `
 +
+ LLaVa-NeXT incorporates a higher input resolution by encoding various patches of the input image. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/haotian-liu/LLaVA/tree/main).
+
+## Usage tips
+
+- We advise users to use `padding_side="left"` when computing batched generation as it leads to more accurate results. Simply make sure to call `processor.tokenizer.padding_side = "left"` before generating.
+
+
 +
 +
+ MarkupLM architecture. Taken from the original paper.
+
+## Usage: MarkupLMProcessor
+
+The easiest way to prepare data for the model is to use [`MarkupLMProcessor`], which internally combines a feature extractor
+([`MarkupLMFeatureExtractor`]) and a tokenizer ([`MarkupLMTokenizer`] or [`MarkupLMTokenizerFast`]). The feature extractor is
+used to extract all nodes and xpaths from the HTML strings, which are then provided to the tokenizer, which turns them into the
+token-level inputs of the model (`input_ids` etc.). Note that you can still use the feature extractor and tokenizer separately,
+if you only want to handle one of the two tasks.
+
+```python
+from transformers import MarkupLMFeatureExtractor, MarkupLMTokenizerFast, MarkupLMProcessor
+
+feature_extractor = MarkupLMFeatureExtractor()
+tokenizer = MarkupLMTokenizerFast.from_pretrained("microsoft/markuplm-base")
+processor = MarkupLMProcessor(feature_extractor, tokenizer)
+```
+
+In short, one can provide HTML strings (and possibly additional data) to [`MarkupLMProcessor`],
+and it will create the inputs expected by the model. Internally, the processor first uses
+[`MarkupLMFeatureExtractor`] to get a list of nodes and corresponding xpaths. The nodes and
+xpaths are then provided to [`MarkupLMTokenizer`] or [`MarkupLMTokenizerFast`], which converts them
+to token-level `input_ids`, `attention_mask`, `token_type_ids`, `xpath_subs_seq`, `xpath_tags_seq`.
+Optionally, one can provide node labels to the processor, which are turned into token-level `labels`.
+
+[`MarkupLMFeatureExtractor`] uses [Beautiful Soup](https://www.crummy.com/software/BeautifulSoup/bs4/doc/), a Python library for
+pulling data out of HTML and XML files, under the hood. Note that you can still use your own parsing solution of
+choice, and provide the nodes and xpaths yourself to [`MarkupLMTokenizer`] or [`MarkupLMTokenizerFast`].
+
+In total, there are 5 use cases that are supported by the processor. Below, we list them all. Note that each of these
+use cases work for both batched and non-batched inputs (we illustrate them for non-batched inputs).
+
+**Use case 1: web page classification (training, inference) + token classification (inference), parse_html = True**
+
+This is the simplest case, in which the processor will use the feature extractor to get all nodes and xpaths from the HTML.
+
+```python
+>>> from transformers import MarkupLMProcessor
+
+>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
+
+>>> html_string = """
+...
+...
+...
+...
 +
+ Mask2Former architecture. Taken from the original paper.
+
+This model was contributed by [Shivalika Singh](https://huggingface.co/shivi) and [Alara Dirik](https://huggingface.co/adirik). The original code can be found [here](https://github.com/facebookresearch/Mask2Former).
+
+## Usage tips
+
+- Mask2Former uses the same preprocessing and postprocessing steps as [MaskFormer](maskformer). Use [`Mask2FormerImageProcessor`] or [`AutoImageProcessor`] to prepare images and optional targets for the model.
+- To get the final segmentation, depending on the task, you can call [`~Mask2FormerImageProcessor.post_process_semantic_segmentation`] or [`~Mask2FormerImageProcessor.post_process_instance_segmentation`] or [`~Mask2FormerImageProcessor.post_process_panoptic_segmentation`]. All three tasks can be solved using [`Mask2FormerForUniversalSegmentation`] output, panoptic segmentation accepts an optional `label_ids_to_fuse` argument to fuse instances of the target object/s (e.g. sky) together.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Mask2Former.
+
+- Demo notebooks regarding inference + fine-tuning Mask2Former on custom data can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Mask2Former).
+- Scripts for finetuning [`Mask2Former`] with [`Trainer`] or [Accelerate](https://huggingface.co/docs/accelerate/index) can be found [here](https://github.com/huggingface/transformers/tree/main/examples/pytorch/instance-segmentation).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we will review it.
+The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## Mask2FormerConfig
+
+[[autodoc]] Mask2FormerConfig
+
+## MaskFormer specific outputs
+
+[[autodoc]] models.mask2former.modeling_mask2former.Mask2FormerModelOutput
+
+[[autodoc]] models.mask2former.modeling_mask2former.Mask2FormerForUniversalSegmentationOutput
+
+## Mask2FormerModel
+
+[[autodoc]] Mask2FormerModel
+ - forward
+
+## Mask2FormerForUniversalSegmentation
+
+[[autodoc]] Mask2FormerForUniversalSegmentation
+ - forward
+
+## Mask2FormerImageProcessor
+
+[[autodoc]] Mask2FormerImageProcessor
+ - preprocess
+ - encode_inputs
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/maskformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/maskformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..a0199f380ce647e70d49d852f194bdcad5e31476
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/maskformer.md
@@ -0,0 +1,92 @@
+
+
+# MaskFormer
+
+
 +
+This model was contributed by [francesco](https://huggingface.co/francesco). The original code can be found [here](https://github.com/facebookresearch/MaskFormer).
+
+## Usage tips
+
+- MaskFormer's Transformer decoder is identical to the decoder of [DETR](detr). During training, the authors of DETR did find it helpful to use auxiliary losses in the decoder, especially to help the model output the correct number of objects of each class. If you set the parameter `use_auxiliary_loss` of [`MaskFormerConfig`] to `True`, then prediction feedforward neural networks and Hungarian losses are added after each decoder layer (with the FFNs sharing parameters).
+- If you want to train the model in a distributed environment across multiple nodes, then one should update the
+ `get_num_masks` function inside in the `MaskFormerLoss` class of `modeling_maskformer.py`. When training on multiple nodes, this should be
+ set to the average number of target masks across all nodes, as can be seen in the original implementation [here](https://github.com/facebookresearch/MaskFormer/blob/da3e60d85fdeedcb31476b5edd7d328826ce56cc/mask_former/modeling/criterion.py#L169).
+- One can use [`MaskFormerImageProcessor`] to prepare images for the model and optional targets for the model.
+- To get the final segmentation, depending on the task, you can call [`~MaskFormerImageProcessor.post_process_semantic_segmentation`] or [`~MaskFormerImageProcessor.post_process_panoptic_segmentation`]. Both tasks can be solved using [`MaskFormerForInstanceSegmentation`] output, panoptic segmentation accepts an optional `label_ids_to_fuse` argument to fuse instances of the target object/s (e.g. sky) together.
+
+## Resources
+
+
 +
+ MGP-STR architecture. Taken from the original paper.
+
+MGP-STR is trained on two synthetic datasets [MJSynth]((http://www.robots.ox.ac.uk/~vgg/data/text/)) (MJ) and [SynthText](http://www.robots.ox.ac.uk/~vgg/data/scenetext/) (ST) without fine-tuning on other datasets. It achieves state-of-the-art results on six standard Latin scene text benchmarks, including 3 regular text datasets (IC13, SVT, IIIT) and 3 irregular ones (IC15, SVTP, CUTE).
+This model was contributed by [yuekun](https://huggingface.co/yuekun). The original code can be found [here](https://github.com/AlibabaResearch/AdvancedLiterateMachinery/tree/main/OCR/MGP-STR).
+
+## Inference example
+
+[`MgpstrModel`] accepts images as input and generates three types of predictions, which represent textual information at different granularities.
+The three types of predictions are fused to give the final prediction result.
+
+The [`ViTImageProcessor`] class is responsible for preprocessing the input image and
+[`MgpstrTokenizer`] decodes the generated character tokens to the target string. The
+[`MgpstrProcessor`] wraps [`ViTImageProcessor`] and [`MgpstrTokenizer`]
+into a single instance to both extract the input features and decode the predicted token ids.
+
+- Step-by-step Optical Character Recognition (OCR)
+
+```py
+>>> from transformers import MgpstrProcessor, MgpstrForSceneTextRecognition
+>>> import requests
+>>> from PIL import Image
+
+>>> processor = MgpstrProcessor.from_pretrained('alibaba-damo/mgp-str-base')
+>>> model = MgpstrForSceneTextRecognition.from_pretrained('alibaba-damo/mgp-str-base')
+
+>>> # load image from the IIIT-5k dataset
+>>> url = "https://i.postimg.cc/ZKwLg2Gw/367-14.png"
+>>> image = Image.open(requests.get(url, stream=True).raw).convert("RGB")
+
+>>> pixel_values = processor(images=image, return_tensors="pt").pixel_values
+>>> outputs = model(pixel_values)
+
+>>> generated_text = processor.batch_decode(outputs.logits)['generated_text']
+```
+
+## MgpstrConfig
+
+[[autodoc]] MgpstrConfig
+
+## MgpstrTokenizer
+
+[[autodoc]] MgpstrTokenizer
+ - save_vocabulary
+
+## MgpstrProcessor
+
+[[autodoc]] MgpstrProcessor
+ - __call__
+ - batch_decode
+
+## MgpstrModel
+
+[[autodoc]] MgpstrModel
+ - forward
+
+## MgpstrForSceneTextRecognition
+
+[[autodoc]] MgpstrForSceneTextRecognition
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mimi.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mimi.md
new file mode 100644
index 0000000000000000000000000000000000000000..ad15a002da916625e5057d1b6bf1b861802510dc
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mimi.md
@@ -0,0 +1,69 @@
+
+
+# Mimi
+
+## Overview
+
+The Mimi model was proposed in [Moshi: a speech-text foundation model for real-time dialogue](https://kyutai.org/Moshi.pdf) by Alexandre Défossez, Laurent Mazaré, Manu Orsini, Amélie Royer, Patrick Pérez, Hervé Jégou, Edouard Grave and Neil Zeghidour. Mimi is a high-fidelity audio codec model developed by the Kyutai team, that combines semantic and acoustic information into audio tokens running at 12Hz and a bitrate of 1.1kbps. In other words, it can be used to map audio waveforms into “audio tokens”, known as “codebooks”.
+
+The abstract from the paper is the following:
+
+*We introduce Moshi, a speech-text foundation model and full-duplex spoken dialogue framework. Current systems for spoken dialogue rely on pipelines of independent components, namely voice activity detection, speech recognition, textual dialogue and text-to-speech. Such frameworks cannot emulate the experience of real conversations. First, their complexity induces a latency of several seconds between interactions. Second, text being the intermediate modality for dialogue, non-linguistic information that modifies meaning— such as emotion or non-speech sounds— is lost in the interaction. Finally, they rely on a segmentation into speaker turns, which does not take into account overlapping speech, interruptions and interjections. Moshi solves these independent issues altogether by casting spoken dialogue as speech-to-speech generation. Starting from a text language model backbone, Moshi generates speech as tokens from the residual quantizer of a neural audio codec, while modeling separately its own speech and that of the user into parallel streams. This allows for the removal of explicit speaker turns, and the modeling of arbitrary conversational dynamics. We moreover extend the hierarchical semantic-to-acoustic token generation of previous work to first predict time-aligned text tokens as a prefix to audio tokens. Not only this “Inner Monologue” method significantly improves the linguistic quality of generated speech, but we also illustrate how it can provide streaming speech recognition and text-to-speech. Our resulting model is the first real-time full-duplex spoken large language model, with a theoretical latency of 160ms, 200ms in practice, and is available at github.com/kyutai-labs/moshi.*
+
+Its architecture is based on [Encodec](model_doc/encodec) with several major differences:
+* it uses a much lower frame-rate.
+* it uses additional transformers for encoding and decoding for better latent contextualization
+* it uses a different quantization scheme: one codebook is dedicated to semantic projection.
+
+## Usage example
+
+Here is a quick example of how to encode and decode an audio using this model:
+
+```python
+>>> from datasets import load_dataset, Audio
+>>> from transformers import MimiModel, AutoFeatureExtractor
+>>> librispeech_dummy = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+
+>>> # load model and feature extractor
+>>> model = MimiModel.from_pretrained("kyutai/mimi")
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("kyutai/mimi")
+
+>>> # load audio sample
+>>> librispeech_dummy = librispeech_dummy.cast_column("audio", Audio(sampling_rate=feature_extractor.sampling_rate))
+>>> audio_sample = librispeech_dummy[-1]["audio"]["array"]
+>>> inputs = feature_extractor(raw_audio=audio_sample, sampling_rate=feature_extractor.sampling_rate, return_tensors="pt")
+
+>>> encoder_outputs = model.encode(inputs["input_values"], inputs["padding_mask"])
+>>> audio_values = model.decode(encoder_outputs.audio_codes, inputs["padding_mask"])[0]
+>>> # or the equivalent with a forward pass
+>>> audio_values = model(inputs["input_values"], inputs["padding_mask"]).audio_values
+```
+
+This model was contributed by [Yoach Lacombe (ylacombe)](https://huggingface.co/ylacombe).
+The original code can be found [here](https://github.com/kyutai-labs/moshi).
+
+
+## MimiConfig
+
+[[autodoc]] MimiConfig
+
+## MimiModel
+
+[[autodoc]] MimiModel
+ - decode
+ - encode
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mistral.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mistral.md
new file mode 100644
index 0000000000000000000000000000000000000000..cfa2af3678137a719af30898bc41ff94a170b548
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/mistral.md
@@ -0,0 +1,239 @@
+
+
+# Mistral
+
+## Overview
+
+Mistral was introduced in the [this blogpost](https://mistral.ai/news/announcing-mistral-7b/) by Albert Jiang, Alexandre Sablayrolles, Arthur Mensch, Chris Bamford, Devendra Singh Chaplot, Diego de las Casas, Florian Bressand, Gianna Lengyel, Guillaume Lample, Lélio Renard Lavaud, Lucile Saulnier, Marie-Anne Lachaux, Pierre Stock, Teven Le Scao, Thibaut Lavril, Thomas Wang, Timothée Lacroix, William El Sayed.
+
+The introduction of the blog post says:
+
+*Mistral AI team is proud to release Mistral 7B, the most powerful language model for its size to date.*
+
+Mistral-7B is the first large language model (LLM) released by [mistral.ai](https://mistral.ai/).
+
+### Architectural details
+
+Mistral-7B is a decoder-only Transformer with the following architectural choices:
+
+- Sliding Window Attention - Trained with 8k context length and fixed cache size, with a theoretical attention span of 128K tokens
+- GQA (Grouped Query Attention) - allowing faster inference and lower cache size.
+- Byte-fallback BPE tokenizer - ensures that characters are never mapped to out of vocabulary tokens.
+
+For more details refer to the [release blog post](https://mistral.ai/news/announcing-mistral-7b/).
+
+### License
+
+`Mistral-7B` is released under the Apache 2.0 license.
+
+## Usage tips
+
+The Mistral team has released 3 checkpoints:
+
+- a base model, [Mistral-7B-v0.1](https://huggingface.co/mistralai/Mistral-7B-v0.1), which has been pre-trained to predict the next token on internet-scale data.
+- an instruction tuned model, [Mistral-7B-Instruct-v0.1](https://huggingface.co/mistralai/Mistral-7B-Instruct-v0.1), which is the base model optimized for chat purposes using supervised fine-tuning (SFT) and direct preference optimization (DPO).
+- an improved instruction tuned model, [Mistral-7B-Instruct-v0.2](https://huggingface.co/mistralai/Mistral-7B-Instruct-v0.2), which improves upon v1.
+
+The base model can be used as follows:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-v0.1", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-v0.1")
+
+>>> prompt = "My favourite condiment is"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to("cuda")
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"My favourite condiment is to ..."
+```
+
+The instruction tuned model can be used as follows:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-Instruct-v0.2", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-Instruct-v0.2")
+
+>>> messages = [
+... {"role": "user", "content": "What is your favourite condiment?"},
+... {"role": "assistant", "content": "Well, I'm quite partial to a good squeeze of fresh lemon juice. It adds just the right amount of zesty flavour to whatever I'm cooking up in the kitchen!"},
+... {"role": "user", "content": "Do you have mayonnaise recipes?"}
+... ]
+
+>>> model_inputs = tokenizer.apply_chat_template(messages, return_tensors="pt").to("cuda")
+
+>>> generated_ids = model.generate(model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"Mayonnaise can be made as follows: (...)"
+```
+
+As can be seen, the instruction-tuned model requires a [chat template](../chat_templating) to be applied to make sure the inputs are prepared in the right format.
+
+## Speeding up Mistral by using Flash Attention
+
+The code snippets above showcase inference without any optimization tricks. However, one can drastically speed up the model by leveraging [Flash Attention](../perf_train_gpu_one#flash-attention-2), which is a faster implementation of the attention mechanism used inside the model.
+
+First, make sure to install the latest version of Flash Attention 2 to include the sliding window attention feature.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Make also sure that you have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of the [flash attention repository](https://github.com/Dao-AILab/flash-attention). Make also sure to load your model in half-precision (e.g. `torch.float16`)
+
+To load and run a model using Flash Attention-2, refer to the snippet below:
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-v0.1", torch_dtype=torch.float16, attn_implementation="flash_attention_2", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-v0.1")
+
+>>> prompt = "My favourite condiment is"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to("cuda")
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"My favourite condiment is to (...)"
+```
+
+### Expected speedups
+
+Below is a expected speedup diagram that compares pure inference time between the native implementation in transformers using `mistralai/Mistral-7B-v0.1` checkpoint and the Flash Attention 2 version of the model.
+
+
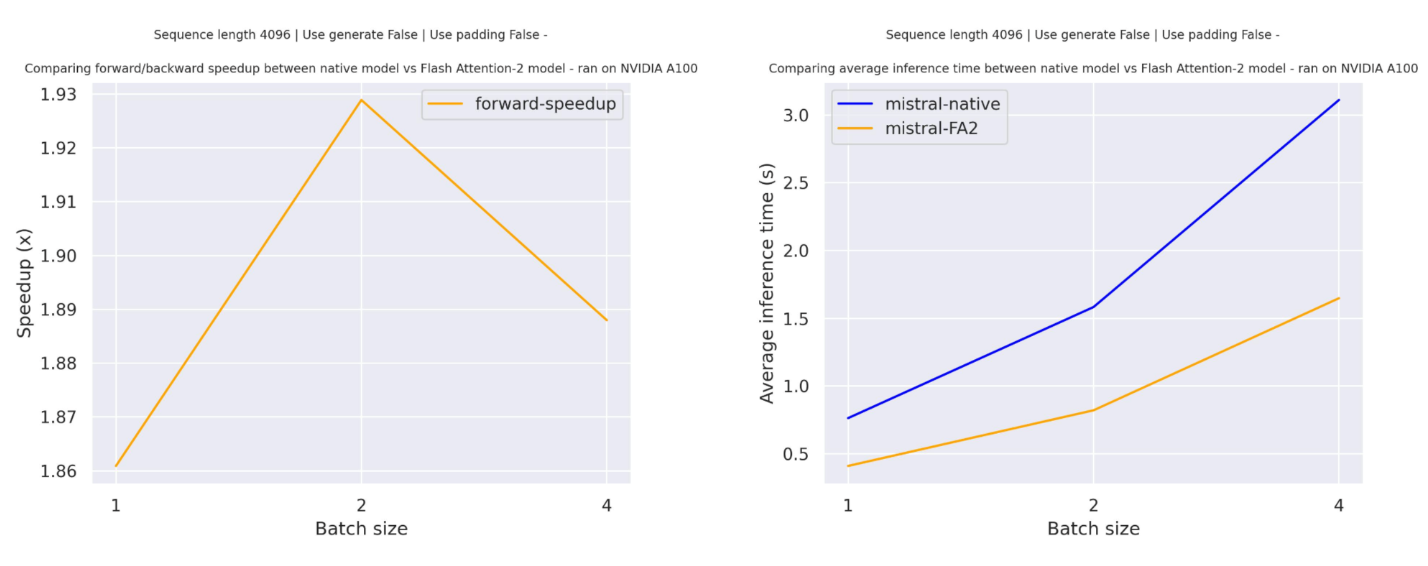 +
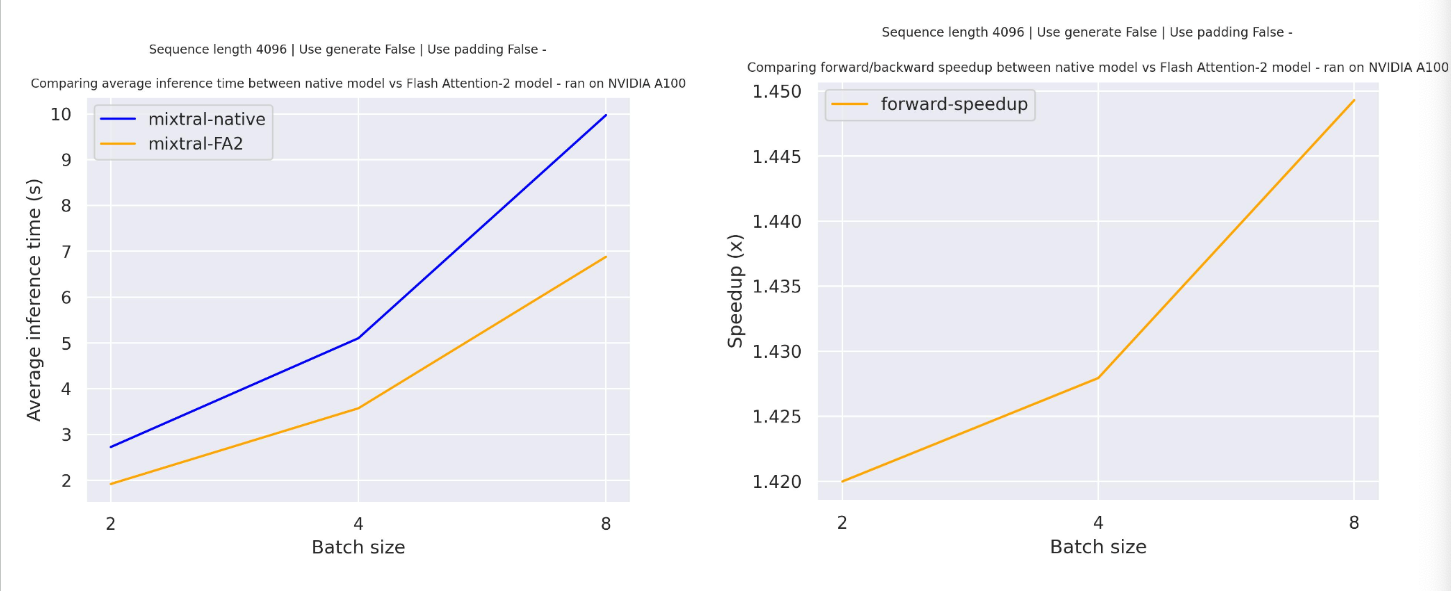 +
 +
 +
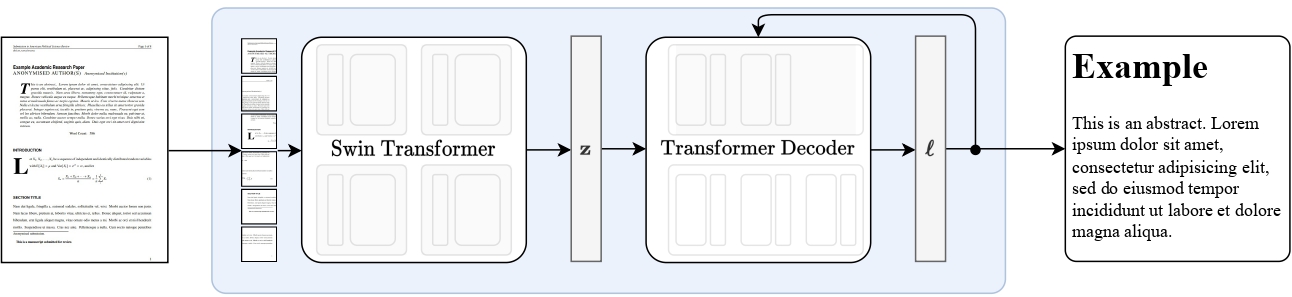 +
+ Nougat high-level overview. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found
+[here](https://github.com/facebookresearch/nougat).
+
+## Usage tips
+
+- The quickest way to get started with Nougat is by checking the [tutorial
+ notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Nougat), which show how to use the model
+ at inference time as well as fine-tuning on custom data.
+- Nougat is always used within the [VisionEncoderDecoder](vision-encoder-decoder) framework. The model is identical to [Donut](donut) in terms of architecture.
+
+## Inference
+
+Nougat's [`VisionEncoderDecoder`] model accepts images as input and makes use of
+[`~generation.GenerationMixin.generate`] to autoregressively generate text given the input image.
+
+The [`NougatImageProcessor`] class is responsible for preprocessing the input image and
+[`NougatTokenizerFast`] decodes the generated target tokens to the target string. The
+[`NougatProcessor`] wraps [`NougatImageProcessor`] and [`NougatTokenizerFast`] classes
+into a single instance to both extract the input features and decode the predicted token ids.
+
+- Step-by-step PDF transcription
+
+```py
+>>> from huggingface_hub import hf_hub_download
+>>> import re
+>>> from PIL import Image
+
+>>> from transformers import NougatProcessor, VisionEncoderDecoderModel
+>>> from datasets import load_dataset
+>>> import torch
+
+>>> processor = NougatProcessor.from_pretrained("facebook/nougat-base")
+>>> model = VisionEncoderDecoderModel.from_pretrained("facebook/nougat-base")
+
+>>> device = "cuda" if torch.cuda.is_available() else "cpu"
+>>> model.to(device) # doctest: +IGNORE_RESULT
+
+>>> # prepare PDF image for the model
+>>> filepath = hf_hub_download(repo_id="hf-internal-testing/fixtures_docvqa", filename="nougat_paper.png", repo_type="dataset")
+>>> image = Image.open(filepath)
+>>> pixel_values = processor(image, return_tensors="pt").pixel_values
+
+>>> # generate transcription (here we only generate 30 tokens)
+>>> outputs = model.generate(
+... pixel_values.to(device),
+... min_length=1,
+... max_new_tokens=30,
+... bad_words_ids=[[processor.tokenizer.unk_token_id]],
+... )
+
+>>> sequence = processor.batch_decode(outputs, skip_special_tokens=True)[0]
+>>> sequence = processor.post_process_generation(sequence, fix_markdown=False)
+>>> # note: we're using repr here such for the sake of printing the \n characters, feel free to just print the sequence
+>>> print(repr(sequence))
+'\n\n# Nougat: Neural Optical Understanding for Academic Documents\n\n Lukas Blecher\n\nCorrespondence to: lblecher@'
+```
+
+See the [model hub](https://huggingface.co/models?filter=nougat) to look for Nougat checkpoints.
+
+
 +
+ OmDet-Turbo architecture overview. Taken from the original paper.
+
+This model was contributed by [yonigozlan](https://huggingface.co/yonigozlan).
+The original code can be found [here](https://github.com/om-ai-lab/OmDet).
+
+## Usage tips
+
+One unique property of OmDet-Turbo compared to other zero-shot object detection models, such as [Grounding DINO](grounding-dino), is the decoupled classes and prompt embedding structure that allows caching of text embeddings. This means that the model needs both classes and task as inputs, where classes is a list of objects we want to detect and task is the grounded text used to guide open-vocabulary detection. This approach limits the scope of the open-vocabulary detection and makes the decoding process faster.
+
+[`OmDetTurboProcessor`] is used to prepare the classes, task and image triplet. The task input is optional, and when not provided, it will default to `"Detect [class1], [class2], [class3], ..."`. To process the results from the model, one can use `post_process_grounded_object_detection` from [`OmDetTurboProcessor`]. Notably, this function takes in the input classes, as unlike other zero-shot object detection models, the decoupling of classes and task embeddings means that no decoding of the predicted class embeddings is needed in the post-processing step, and the predicted classes can be matched to the inputted ones directly.
+
+## Usage example
+
+### Single image inference
+
+Here's how to load the model and prepare the inputs to perform zero-shot object detection on a single image:
+
+```python
+import requests
+from PIL import Image
+
+from transformers import AutoProcessor, OmDetTurboForObjectDetection
+
+processor = AutoProcessor.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+model = OmDetTurboForObjectDetection.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+classes = ["cat", "remote"]
+inputs = processor(image, text=classes, return_tensors="pt")
+
+outputs = model(**inputs)
+
+# convert outputs (bounding boxes and class logits)
+results = processor.post_process_grounded_object_detection(
+ outputs,
+ classes=classes,
+ target_sizes=[image.size[::-1]],
+ score_threshold=0.3,
+ nms_threshold=0.3,
+)[0]
+for score, class_name, box in zip(
+ results["scores"], results["classes"], results["boxes"]
+):
+ box = [round(i, 1) for i in box.tolist()]
+ print(
+ f"Detected {class_name} with confidence "
+ f"{round(score.item(), 2)} at location {box}"
+ )
+```
+
+### Multi image inference
+
+OmDet-Turbo can perform batched multi-image inference, with support for different text prompts and classes in the same batch:
+
+```python
+>>> import torch
+>>> import requests
+>>> from io import BytesIO
+>>> from PIL import Image
+>>> from transformers import AutoProcessor, OmDetTurboForObjectDetection
+
+>>> processor = AutoProcessor.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+>>> model = OmDetTurboForObjectDetection.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+
+>>> url1 = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image1 = Image.open(BytesIO(requests.get(url1).content)).convert("RGB")
+>>> classes1 = ["cat", "remote"]
+>>> task1 = "Detect {}.".format(", ".join(classes1))
+
+>>> url2 = "http://images.cocodataset.org/train2017/000000257813.jpg"
+>>> image2 = Image.open(BytesIO(requests.get(url2).content)).convert("RGB")
+>>> classes2 = ["boat"]
+>>> task2 = "Detect everything that looks like a boat."
+
+>>> url3 = "https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg"
+>>> image3 = Image.open(BytesIO(requests.get(url3).content)).convert("RGB")
+>>> classes3 = ["statue", "trees"]
+>>> task3 = "Focus on the foreground, detect statue and trees."
+
+>>> inputs = processor(
+... images=[image1, image2, image3],
+... text=[classes1, classes2, classes3],
+... task=[task1, task2, task3],
+... return_tensors="pt",
+... )
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> # convert outputs (bounding boxes and class logits)
+>>> results = processor.post_process_grounded_object_detection(
+... outputs,
+... classes=[classes1, classes2, classes3],
+... target_sizes=[image1.size[::-1], image2.size[::-1], image3.size[::-1]],
+... score_threshold=0.2,
+... nms_threshold=0.3,
+... )
+
+>>> for i, result in enumerate(results):
+... for score, class_name, box in zip(
+... result["scores"], result["classes"], result["boxes"]
+... ):
+... box = [round(i, 1) for i in box.tolist()]
+... print(
+... f"Detected {class_name} with confidence "
+... f"{round(score.item(), 2)} at location {box} in image {i}"
+... )
+Detected remote with confidence 0.77 at location [39.9, 70.4, 176.7, 118.0] in image 0
+Detected cat with confidence 0.72 at location [11.6, 54.2, 314.8, 474.0] in image 0
+Detected remote with confidence 0.56 at location [333.4, 75.8, 370.7, 187.0] in image 0
+Detected cat with confidence 0.55 at location [345.2, 24.0, 639.8, 371.7] in image 0
+Detected boat with confidence 0.32 at location [146.9, 219.8, 209.6, 250.7] in image 1
+Detected boat with confidence 0.3 at location [319.1, 223.2, 403.2, 238.4] in image 1
+Detected boat with confidence 0.27 at location [37.7, 220.3, 84.0, 235.9] in image 1
+Detected boat with confidence 0.22 at location [407.9, 207.0, 441.7, 220.2] in image 1
+Detected statue with confidence 0.73 at location [544.7, 210.2, 651.9, 502.8] in image 2
+Detected trees with confidence 0.25 at location [3.9, 584.3, 391.4, 785.6] in image 2
+Detected trees with confidence 0.25 at location [1.4, 621.2, 118.2, 787.8] in image 2
+Detected statue with confidence 0.2 at location [428.1, 205.5, 767.3, 759.5] in image 2
+
+```
+
+## OmDetTurboConfig
+
+[[autodoc]] OmDetTurboConfig
+
+## OmDetTurboProcessor
+
+[[autodoc]] OmDetTurboProcessor
+ - post_process_grounded_object_detection
+
+## OmDetTurboForObjectDetection
+
+[[autodoc]] OmDetTurboForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/oneformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/oneformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..0132a600ccc5e531b9a1d1110ff9ced91c8414ac
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/oneformer.md
@@ -0,0 +1,86 @@
+
+
+# OneFormer
+
+## Overview
+
+The OneFormer model was proposed in [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi. OneFormer is a universal image segmentation framework that can be trained on a single panoptic dataset to perform semantic, instance, and panoptic segmentation tasks. OneFormer uses a task token to condition the model on the task in focus, making the architecture task-guided for training, and task-dynamic for inference.
+
+
 +
+The abstract from the paper is the following:
+
+*Universal Image Segmentation is not a new concept. Past attempts to unify image segmentation in the last decades include scene parsing, panoptic segmentation, and, more recently, new panoptic architectures. However, such panoptic architectures do not truly unify image segmentation because they need to be trained individually on the semantic, instance, or panoptic segmentation to achieve the best performance. Ideally, a truly universal framework should be trained only once and achieve SOTA performance across all three image segmentation tasks. To that end, we propose OneFormer, a universal image segmentation framework that unifies segmentation with a multi-task train-once design. We first propose a task-conditioned joint training strategy that enables training on ground truths of each domain (semantic, instance, and panoptic segmentation) within a single multi-task training process. Secondly, we introduce a task token to condition our model on the task at hand, making our model task-dynamic to support multi-task training and inference. Thirdly, we propose using a query-text contrastive loss during training to establish better inter-task and inter-class distinctions. Notably, our single OneFormer model outperforms specialized Mask2Former models across all three segmentation tasks on ADE20k, CityScapes, and COCO, despite the latter being trained on each of the three tasks individually with three times the resources. With new ConvNeXt and DiNAT backbones, we observe even more performance improvement. We believe OneFormer is a significant step towards making image segmentation more universal and accessible.*
+
+The figure below illustrates the architecture of OneFormer. Taken from the [original paper](https://arxiv.org/abs/2211.06220).
+
+
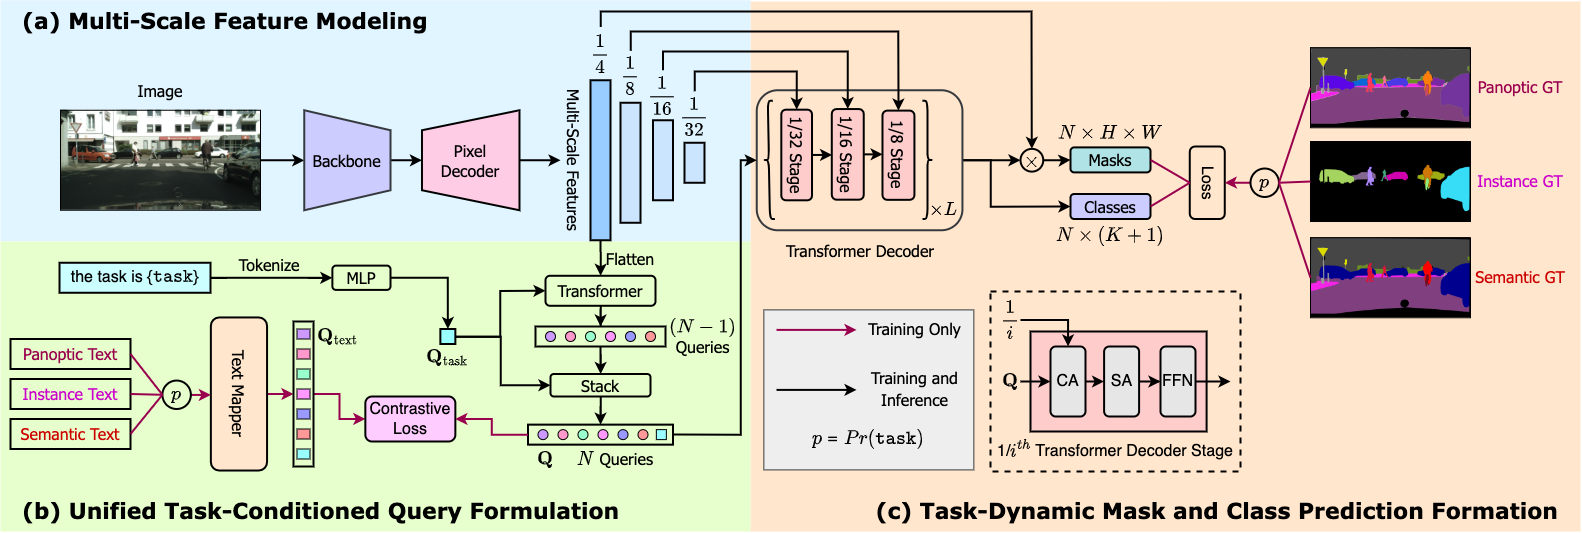 +
+This model was contributed by [Jitesh Jain](https://huggingface.co/praeclarumjj3). The original code can be found [here](https://github.com/SHI-Labs/OneFormer).
+
+## Usage tips
+
+- OneFormer requires two inputs during inference: *image* and *task token*.
+- During training, OneFormer only uses panoptic annotations.
+- If you want to train the model in a distributed environment across multiple nodes, then one should update the
+ `get_num_masks` function inside in the `OneFormerLoss` class of `modeling_oneformer.py`. When training on multiple nodes, this should be
+ set to the average number of target masks across all nodes, as can be seen in the original implementation [here](https://github.com/SHI-Labs/OneFormer/blob/33ebb56ed34f970a30ae103e786c0cb64c653d9a/oneformer/modeling/criterion.py#L287).
+- One can use [`OneFormerProcessor`] to prepare input images and task inputs for the model and optional targets for the model. [`OneFormerProcessor`] wraps [`OneFormerImageProcessor`] and [`CLIPTokenizer`] into a single instance to both prepare the images and encode the task inputs.
+- To get the final segmentation, depending on the task, you can call [`~OneFormerProcessor.post_process_semantic_segmentation`] or [`~OneFormerImageProcessor.post_process_instance_segmentation`] or [`~OneFormerImageProcessor.post_process_panoptic_segmentation`]. All three tasks can be solved using [`OneFormerForUniversalSegmentation`] output, panoptic segmentation accepts an optional `label_ids_to_fuse` argument to fuse instances of the target object/s (e.g. sky) together.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with OneFormer.
+
+- Demo notebooks regarding inference + fine-tuning on custom data can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/OneFormer).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we will review it.
+The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## OneFormer specific outputs
+
+[[autodoc]] models.oneformer.modeling_oneformer.OneFormerModelOutput
+
+[[autodoc]] models.oneformer.modeling_oneformer.OneFormerForUniversalSegmentationOutput
+
+## OneFormerConfig
+
+[[autodoc]] OneFormerConfig
+
+## OneFormerImageProcessor
+
+[[autodoc]] OneFormerImageProcessor
+ - preprocess
+ - encode_inputs
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## OneFormerProcessor
+
+[[autodoc]] OneFormerProcessor
+
+## OneFormerModel
+
+[[autodoc]] OneFormerModel
+ - forward
+
+## OneFormerForUniversalSegmentation
+
+[[autodoc]] OneFormerForUniversalSegmentation
+ - forward
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/open-llama.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/open-llama.md
new file mode 100644
index 0000000000000000000000000000000000000000..01170e7e3be60ffb7e5fe597457b7b130178539c
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/open-llama.md
@@ -0,0 +1,61 @@
+
+
+# Open-Llama
+
+
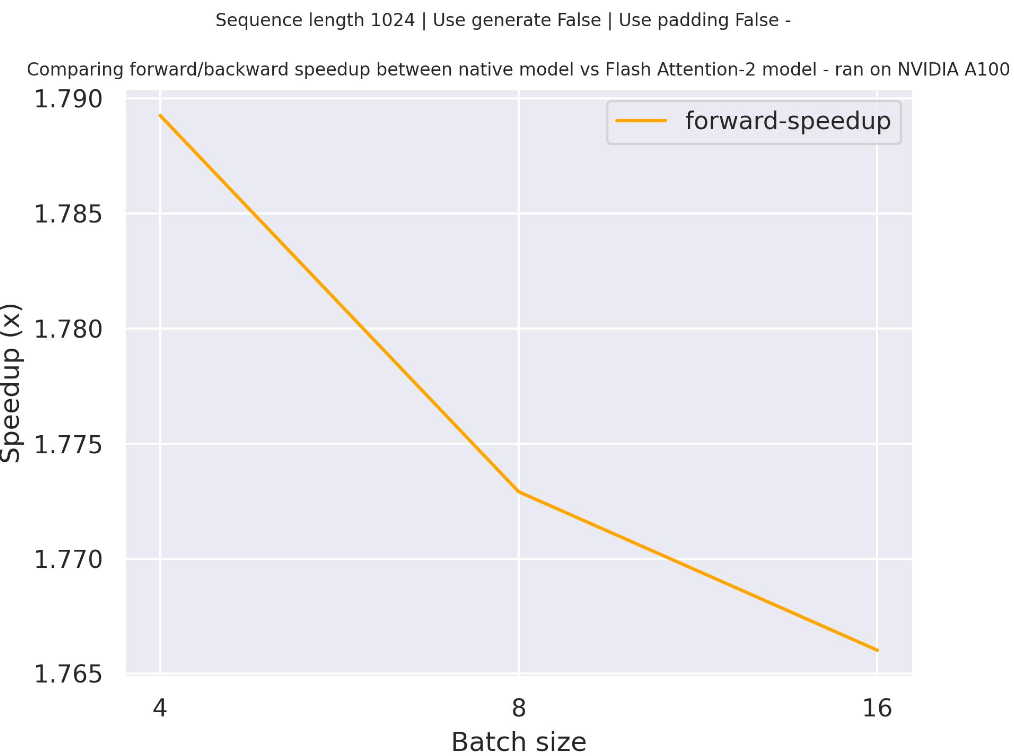 +
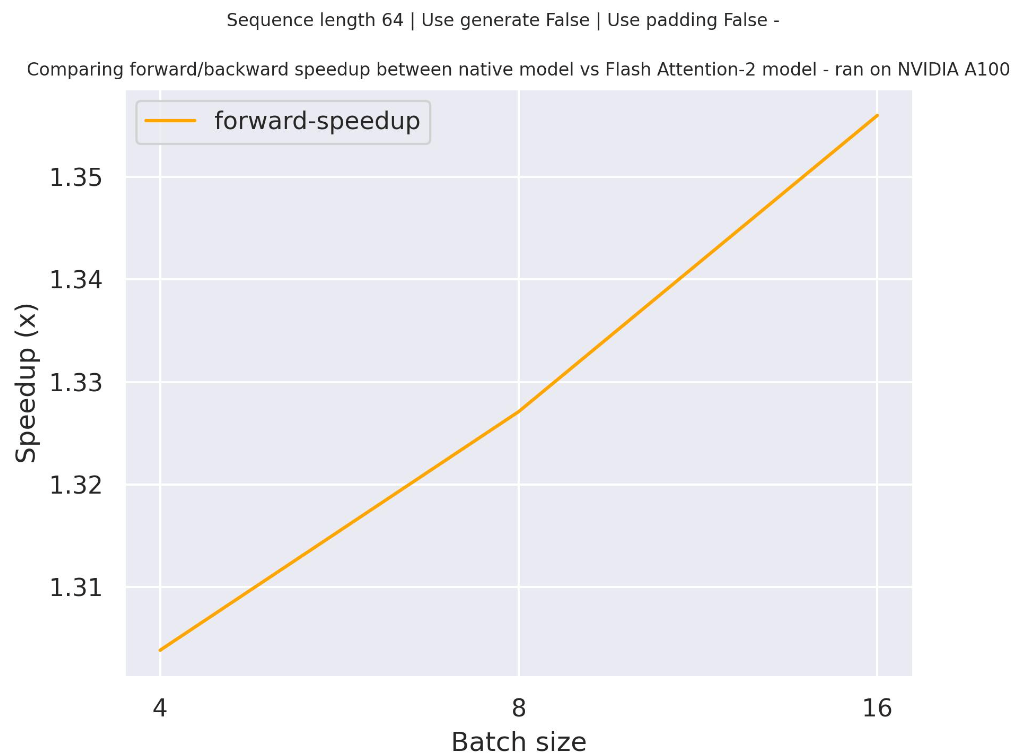 +
 +
+ OWLv2 high-level overview. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/google-research/scenic/tree/main/scenic/projects/owl_vit).
+
+## Usage example
+
+OWLv2 is, just like its predecessor [OWL-ViT](owlvit), a zero-shot text-conditioned object detection model. OWL-ViT uses [CLIP](clip) as its multi-modal backbone, with a ViT-like Transformer to get visual features and a causal language model to get the text features. To use CLIP for detection, OWL-ViT removes the final token pooling layer of the vision model and attaches a lightweight classification and box head to each transformer output token. Open-vocabulary classification is enabled by replacing the fixed classification layer weights with the class-name embeddings obtained from the text model. The authors first train CLIP from scratch and fine-tune it end-to-end with the classification and box heads on standard detection datasets using a bipartite matching loss. One or multiple text queries per image can be used to perform zero-shot text-conditioned object detection.
+
+[`Owlv2ImageProcessor`] can be used to resize (or rescale) and normalize images for the model and [`CLIPTokenizer`] is used to encode the text. [`Owlv2Processor`] wraps [`Owlv2ImageProcessor`] and [`CLIPTokenizer`] into a single instance to both encode the text and prepare the images. The following example shows how to perform object detection using [`Owlv2Processor`] and [`Owlv2ForObjectDetection`].
+
+```python
+>>> import requests
+>>> from PIL import Image
+>>> import torch
+
+>>> from transformers import Owlv2Processor, Owlv2ForObjectDetection
+
+>>> processor = Owlv2Processor.from_pretrained("google/owlv2-base-patch16-ensemble")
+>>> model = Owlv2ForObjectDetection.from_pretrained("google/owlv2-base-patch16-ensemble")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> texts = [["a photo of a cat", "a photo of a dog"]]
+>>> inputs = processor(text=texts, images=image, return_tensors="pt")
+>>> outputs = model(**inputs)
+
+>>> # Target image sizes (height, width) to rescale box predictions [batch_size, 2]
+>>> target_sizes = torch.Tensor([image.size[::-1]])
+>>> # Convert outputs (bounding boxes and class logits) to Pascal VOC Format (xmin, ymin, xmax, ymax)
+>>> results = processor.post_process_object_detection(outputs=outputs, target_sizes=target_sizes, threshold=0.1)
+>>> i = 0 # Retrieve predictions for the first image for the corresponding text queries
+>>> text = texts[i]
+>>> boxes, scores, labels = results[i]["boxes"], results[i]["scores"], results[i]["labels"]
+>>> for box, score, label in zip(boxes, scores, labels):
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"Detected {text[label]} with confidence {round(score.item(), 3)} at location {box}")
+Detected a photo of a cat with confidence 0.614 at location [341.67, 23.39, 642.32, 371.35]
+Detected a photo of a cat with confidence 0.665 at location [6.75, 51.96, 326.62, 473.13]
+```
+
+## Resources
+
+- A demo notebook on using OWLv2 for zero- and one-shot (image-guided) object detection can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/OWLv2).
+- [Zero-shot object detection task guide](../tasks/zero_shot_object_detection)
+
+
 +
+ OWL-ViT architecture. Taken from the original paper.
+
+This model was contributed by [adirik](https://huggingface.co/adirik). The original code can be found [here](https://github.com/google-research/scenic/tree/main/scenic/projects/owl_vit).
+
+## Usage tips
+
+OWL-ViT is a zero-shot text-conditioned object detection model. OWL-ViT uses [CLIP](clip) as its multi-modal backbone, with a ViT-like Transformer to get visual features and a causal language model to get the text features. To use CLIP for detection, OWL-ViT removes the final token pooling layer of the vision model and attaches a lightweight classification and box head to each transformer output token. Open-vocabulary classification is enabled by replacing the fixed classification layer weights with the class-name embeddings obtained from the text model. The authors first train CLIP from scratch and fine-tune it end-to-end with the classification and box heads on standard detection datasets using a bipartite matching loss. One or multiple text queries per image can be used to perform zero-shot text-conditioned object detection.
+
+[`OwlViTImageProcessor`] can be used to resize (or rescale) and normalize images for the model and [`CLIPTokenizer`] is used to encode the text. [`OwlViTProcessor`] wraps [`OwlViTImageProcessor`] and [`CLIPTokenizer`] into a single instance to both encode the text and prepare the images. The following example shows how to perform object detection using [`OwlViTProcessor`] and [`OwlViTForObjectDetection`].
+
+```python
+>>> import requests
+>>> from PIL import Image
+>>> import torch
+
+>>> from transformers import OwlViTProcessor, OwlViTForObjectDetection
+
+>>> processor = OwlViTProcessor.from_pretrained("google/owlvit-base-patch32")
+>>> model = OwlViTForObjectDetection.from_pretrained("google/owlvit-base-patch32")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> texts = [["a photo of a cat", "a photo of a dog"]]
+>>> inputs = processor(text=texts, images=image, return_tensors="pt")
+>>> outputs = model(**inputs)
+
+>>> # Target image sizes (height, width) to rescale box predictions [batch_size, 2]
+>>> target_sizes = torch.Tensor([image.size[::-1]])
+>>> # Convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax)
+>>> results = processor.post_process_object_detection(outputs=outputs, target_sizes=target_sizes, threshold=0.1)
+>>> i = 0 # Retrieve predictions for the first image for the corresponding text queries
+>>> text = texts[i]
+>>> boxes, scores, labels = results[i]["boxes"], results[i]["scores"], results[i]["labels"]
+>>> for box, score, label in zip(boxes, scores, labels):
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"Detected {text[label]} with confidence {round(score.item(), 3)} at location {box}")
+Detected a photo of a cat with confidence 0.707 at location [324.97, 20.44, 640.58, 373.29]
+Detected a photo of a cat with confidence 0.717 at location [1.46, 55.26, 315.55, 472.17]
+```
+
+## Resources
+
+A demo notebook on using OWL-ViT for zero- and one-shot (image-guided) object detection can be found [here](https://github.com/huggingface/notebooks/blob/main/examples/zeroshot_object_detection_with_owlvit.ipynb).
+
+## OwlViTConfig
+
+[[autodoc]] OwlViTConfig
+ - from_text_vision_configs
+
+## OwlViTTextConfig
+
+[[autodoc]] OwlViTTextConfig
+
+## OwlViTVisionConfig
+
+[[autodoc]] OwlViTVisionConfig
+
+## OwlViTImageProcessor
+
+[[autodoc]] OwlViTImageProcessor
+ - preprocess
+ - post_process_object_detection
+ - post_process_image_guided_detection
+
+## OwlViTFeatureExtractor
+
+[[autodoc]] OwlViTFeatureExtractor
+ - __call__
+ - post_process
+ - post_process_image_guided_detection
+
+## OwlViTProcessor
+
+[[autodoc]] OwlViTProcessor
+
+## OwlViTModel
+
+[[autodoc]] OwlViTModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## OwlViTTextModel
+
+[[autodoc]] OwlViTTextModel
+ - forward
+
+## OwlViTVisionModel
+
+[[autodoc]] OwlViTVisionModel
+ - forward
+
+## OwlViTForObjectDetection
+
+[[autodoc]] OwlViTForObjectDetection
+ - forward
+ - image_guided_detection
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/paligemma.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/paligemma.md
new file mode 100644
index 0000000000000000000000000000000000000000..8b88db39bd71650ae2283d8e60d2c261d10d4b39
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/paligemma.md
@@ -0,0 +1,106 @@
+
+
+# PaliGemma
+
+## Overview
+
+The PaliGemma model was proposed in [PaliGemma – Google's Cutting-Edge Open Vision Language Model](https://huggingface.co/blog/paligemma) by Google. It is a 3B vision-language model composed by a [SigLIP](siglip) vision encoder and a [Gemma](gemma) language decoder linked by a multimodal linear projection. It cuts an image into a fixed number of VIT tokens and prepends it to an optional prompt. One particularity is that the model uses full block attention on all the image tokens plus the input text tokens. It comes in 3 resolutions, 224x224, 448x448 and 896x896 with 3 base models, with 55 fine-tuned versions for different tasks, and 2 mix models.
+
+
 +
+ PaliGemma architecture. Taken from the blog post.
+
+This model was contributed by [Molbap](https://huggingface.co/Molbap).
+
+## Usage tips
+
+- PaliGemma is not meant for conversational use, and it works best when fine-tuning to a specific use case. Some downstream tasks on which PaliGemma can be fine-tuned include image captioning, visual question answering (VQA), object detection, referring expression segmentation and document understanding.
+- One can use `PaliGemmaProcessor` to prepare images, text and optional labels for the model. When fine-tuning a PaliGemma model, the `suffix` argument can be passed to the processor which creates the `labels` for the model:
+
+```python
+prompt = "What is on the flower?"
+answer = "a bee"
+inputs = processor(images=raw_image, text=prompt, suffix=answer, return_tensors="pt")
+```
+
+## Usage Example
+
+The model can accept a single or multiple images. According to the [paper](https://arxiv.org/abs/2407.07726v1), the checkpoint PaliGemma can transfer to tasks which take multiple images as input. NLVR2 is one such task, which asks one question about two images, and requires looking at both to give the correct answer. Here's an example code for single and multi image inference.
+
+### Single-image Inference
+
+```python
+from transformers import AutoProcessor, PaliGemmaForConditionalGeneration
+
+model_id = "google/paligemma-3b-mix-224"
+model = PaliGemmaForConditionalGeneration.from_pretrained(model_id)
+processor = AutoProcessor.from_pretrained(model_id)
+
+prompt = "What is on the flower?"
+image_file = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg?download=true"
+raw_image = Image.open(requests.get(image_file, stream=True).raw)
+inputs = processor(raw_image, prompt, return_tensors="pt")
+output = model.generate(**inputs, max_new_tokens=20)
+
+print(processor.decode(output[0], skip_special_tokens=True)[inputs.input_ids.shape[1]: ])
+```
+
+### Multi-image Inference
+
+```python
+model_id = "google/paligemma-3b-ft-nlvr2-448" # checkpoint tuned for multiple images
+model = PaliGemmaForConditionalGeneration.from_pretrained(model_id)
+processor = PaliGemmaProcessor.from_pretrained(model_id)
+
+prompt = "answer en Which of the two pictures shows a snowman, first or second?"
+stop_sign_image = Image.open(
+ requests.get("https://www.ilankelman.org/stopsigns/australia.jpg", stream=True).raw
+)
+snow_image = Image.open(
+ requests.get(
+ "https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/snowman.jpg", stream=True
+ ).raw
+)
+
+inputs = processor(images=[[snow_image, stop_sign_image]], text=prompt, return_tensors="pt")
+
+output = model.generate(**inputs, max_new_tokens=20)
+print(processor.decode(output[0], skip_special_tokens=True)[inputs.input_ids.shape[1]: ])
+
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with PaliGemma. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- A blog post introducing all the features of PaliGemma can be found [here](https://huggingface.co/blog/paligemma).
+- Demo notebooks on how to fine-tune PaliGemma for VQA with the Trainer API along with inference can be found [here](https://github.com/huggingface/notebooks/tree/main/examples/paligemma).
+- Demo notebooks on how to fine-tune PaliGemma on a custom dataset (receipt image -> JSON) along with inference can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/PaliGemma). 🌎
+
+## PaliGemmaConfig
+
+[[autodoc]] PaliGemmaConfig
+
+## PaliGemmaProcessor
+
+[[autodoc]] PaliGemmaProcessor
+
+## PaliGemmaForConditionalGeneration
+
+[[autodoc]] PaliGemmaForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/patchtsmixer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/patchtsmixer.md
new file mode 100644
index 0000000000000000000000000000000000000000..a67138e533b71ad53ad4bfef4537b72da11bb91c
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/patchtsmixer.md
@@ -0,0 +1,94 @@
+
+
+# PatchTSMixer
+
+## Overview
+
+The PatchTSMixer model was proposed in [TSMixer: Lightweight MLP-Mixer Model for Multivariate Time Series Forecasting](https://arxiv.org/pdf/2306.09364.pdf) by Vijay Ekambaram, Arindam Jati, Nam Nguyen, Phanwadee Sinthong and Jayant Kalagnanam.
+
+
+PatchTSMixer is a lightweight time-series modeling approach based on the MLP-Mixer architecture. In this HuggingFace implementation, we provide PatchTSMixer's capabilities to effortlessly facilitate lightweight mixing across patches, channels, and hidden features for effective multivariate time-series modeling. It also supports various attention mechanisms starting from simple gated attention to more complex self-attention blocks that can be customized accordingly. The model can be pretrained and subsequently used for various downstream tasks such as forecasting, classification and regression.
+
+
+The abstract from the paper is the following:
+
+*TSMixer is a lightweight neural architecture exclusively composed of multi-layer perceptron (MLP) modules designed for multivariate forecasting and representation learning on patched time series. Our model draws inspiration from the success of MLP-Mixer models in computer vision. We demonstrate the challenges involved in adapting Vision MLP-Mixer for time series and introduce empirically validated components to enhance accuracy. This includes a novel design paradigm of attaching online reconciliation heads to the MLP-Mixer backbone, for explicitly modeling the time-series properties such as hierarchy and channel-correlations. We also propose a Hybrid channel modeling approach to effectively handle noisy channel interactions and generalization across diverse datasets, a common challenge in existing patch channel-mixing methods. Additionally, a simple gated attention mechanism is introduced in the backbone to prioritize important features. By incorporating these lightweight components, we significantly enhance the learning capability of simple MLP structures, outperforming complex Transformer models with minimal computing usage. Moreover, TSMixer's modular design enables compatibility with both supervised and masked self-supervised learning methods, making it a promising building block for time-series Foundation Models. TSMixer outperforms state-of-the-art MLP and Transformer models in forecasting by a considerable margin of 8-60%. It also outperforms the latest strong benchmarks of Patch-Transformer models (by 1-2%) with a significant reduction in memory and runtime (2-3X).*
+
+This model was contributed by [ajati](https://huggingface.co/ajati), [vijaye12](https://huggingface.co/vijaye12),
+[gsinthong](https://huggingface.co/gsinthong), [namctin](https://huggingface.co/namctin),
+[wmgifford](https://huggingface.co/wmgifford), [kashif](https://huggingface.co/kashif).
+
+## Usage example
+
+The code snippet below shows how to randomly initialize a PatchTSMixer model. The model is compatible with the [Trainer API](../trainer.md).
+
+```python
+
+from transformers import PatchTSMixerConfig, PatchTSMixerForPrediction
+from transformers import Trainer, TrainingArguments,
+
+
+config = PatchTSMixerConfig(context_length = 512, prediction_length = 96)
+model = PatchTSMixerForPrediction(config)
+trainer = Trainer(model=model, args=training_args,
+ train_dataset=train_dataset,
+ eval_dataset=valid_dataset)
+trainer.train()
+results = trainer.evaluate(test_dataset)
+```
+
+## Usage tips
+
+The model can also be used for time series classification and time series regression. See the respective [`PatchTSMixerForTimeSeriesClassification`] and [`PatchTSMixerForRegression`] classes.
+
+## Resources
+
+- A blog post explaining PatchTSMixer in depth can be found [here](https://huggingface.co/blog/patchtsmixer). The blog can also be opened in Google Colab.
+
+## PatchTSMixerConfig
+
+[[autodoc]] PatchTSMixerConfig
+
+
+## PatchTSMixerModel
+
+[[autodoc]] PatchTSMixerModel
+ - forward
+
+
+## PatchTSMixerForPrediction
+
+[[autodoc]] PatchTSMixerForPrediction
+ - forward
+
+
+## PatchTSMixerForTimeSeriesClassification
+
+[[autodoc]] PatchTSMixerForTimeSeriesClassification
+ - forward
+
+
+## PatchTSMixerForPretraining
+
+[[autodoc]] PatchTSMixerForPretraining
+ - forward
+
+
+## PatchTSMixerForRegression
+
+[[autodoc]] PatchTSMixerForRegression
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/patchtst.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/patchtst.md
new file mode 100644
index 0000000000000000000000000000000000000000..544e4cb378c6df3297e2c46d98ace5c1c7be44a1
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/patchtst.md
@@ -0,0 +1,68 @@
+
+
+# PatchTST
+
+## Overview
+
+The PatchTST model was proposed in [A Time Series is Worth 64 Words: Long-term Forecasting with Transformers](https://arxiv.org/abs/2211.14730) by Yuqi Nie, Nam H. Nguyen, Phanwadee Sinthong and Jayant Kalagnanam.
+
+At a high level the model vectorizes time series into patches of a given size and encodes the resulting sequence of vectors via a Transformer that then outputs the prediction length forecast via an appropriate head. The model is illustrated in the following figure:
+
+
+
+The abstract from the paper is the following:
+
+*We propose an efficient design of Transformer-based models for multivariate time series forecasting and self-supervised representation learning. It is based on two key components: (i) segmentation of time series into subseries-level patches which are served as input tokens to Transformer; (ii) channel-independence where each channel contains a single univariate time series that shares the same embedding and Transformer weights across all the series. Patching design naturally has three-fold benefit: local semantic information is retained in the embedding; computation and memory usage of the attention maps are quadratically reduced given the same look-back window; and the model can attend longer history. Our channel-independent patch time series Transformer (PatchTST) can improve the long-term forecasting accuracy significantly when compared with that of SOTA Transformer-based models. We also apply our model to self-supervised pre-training tasks and attain excellent fine-tuning performance, which outperforms supervised training on large datasets. Transferring of masked pre-trained representation on one dataset to others also produces SOTA forecasting accuracy.*
+
+This model was contributed by [namctin](https://huggingface.co/namctin), [gsinthong](https://huggingface.co/gsinthong), [diepi](https://huggingface.co/diepi), [vijaye12](https://huggingface.co/vijaye12), [wmgifford](https://huggingface.co/wmgifford), and [kashif](https://huggingface.co/kashif). The original code can be found [here](https://github.com/yuqinie98/PatchTST).
+
+## Usage tips
+
+The model can also be used for time series classification and time series regression. See the respective [`PatchTSTForClassification`] and [`PatchTSTForRegression`] classes.
+
+## Resources
+
+- A blog post explaining PatchTST in depth can be found [here](https://huggingface.co/blog/patchtst). The blog can also be opened in Google Colab.
+
+## PatchTSTConfig
+
+[[autodoc]] PatchTSTConfig
+
+## PatchTSTModel
+
+[[autodoc]] PatchTSTModel
+ - forward
+
+## PatchTSTForPrediction
+
+[[autodoc]] PatchTSTForPrediction
+ - forward
+
+## PatchTSTForClassification
+
+[[autodoc]] PatchTSTForClassification
+ - forward
+
+## PatchTSTForPretraining
+
+[[autodoc]] PatchTSTForPretraining
+ - forward
+
+## PatchTSTForRegression
+
+[[autodoc]] PatchTSTForRegression
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pegasus.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pegasus.md
new file mode 100644
index 0000000000000000000000000000000000000000..0622354e62dedfb156856da8af3a92a5508ae0db
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/pegasus.md
@@ -0,0 +1,171 @@
+
+
+# Pegasus
+
+
+
+
+## Overview
+
+The Pegasus model was proposed in [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/pdf/1912.08777.pdf) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu on Dec 18, 2019.
+
+According to the abstract,
+
+- Pegasus' pretraining task is intentionally similar to summarization: important sentences are removed/masked from an
+ input document and are generated together as one output sequence from the remaining sentences, similar to an
+ extractive summary.
+- Pegasus achieves SOTA summarization performance on all 12 downstream tasks, as measured by ROUGE and human eval.
+
+This model was contributed by [sshleifer](https://huggingface.co/sshleifer). The Authors' code can be found [here](https://github.com/google-research/pegasus).
+
+## Usage tips
+
+- Sequence-to-sequence model with the same encoder-decoder model architecture as BART. Pegasus is pre-trained jointly on two self-supervised objective functions: Masked Language Modeling (MLM) and a novel summarization specific pretraining objective, called Gap Sentence Generation (GSG).
+
+ * MLM: encoder input tokens are randomly replaced by a mask tokens and have to be predicted by the encoder (like in BERT)
+ * GSG: whole encoder input sentences are replaced by a second mask token and fed to the decoder, but which has a causal mask to hide the future words like a regular auto-regressive transformer decoder.
+
+- FP16 is not supported (help/ideas on this appreciated!).
+- The adafactor optimizer is recommended for pegasus fine-tuning.
+
+
+## Checkpoints
+
+All the [checkpoints](https://huggingface.co/models?search=pegasus) are fine-tuned for summarization, besides
+*pegasus-large*, whence the other checkpoints are fine-tuned:
+
+- Each checkpoint is 2.2 GB on disk and 568M parameters.
+- FP16 is not supported (help/ideas on this appreciated!).
+- Summarizing xsum in fp32 takes about 400ms/sample, with default parameters on a v100 GPU.
+- Full replication results and correctly pre-processed data can be found in this [Issue](https://github.com/huggingface/transformers/issues/6844#issue-689259666).
+- [Distilled checkpoints](https://huggingface.co/models?search=distill-pegasus) are described in this [paper](https://arxiv.org/abs/2010.13002).
+
+## Implementation Notes
+
+- All models are transformer encoder-decoders with 16 layers in each component.
+- The implementation is completely inherited from [`BartForConditionalGeneration`]
+- Some key configuration differences:
+ - static, sinusoidal position embeddings
+ - the model starts generating with pad_token_id (which has 0 token_embedding) as the prefix.
+ - more beams are used (`num_beams=8`)
+- All pretrained pegasus checkpoints are the same besides three attributes: `tokenizer.model_max_length` (maximum
+ input size), `max_length` (the maximum number of tokens to generate) and `length_penalty`.
+- The code to convert checkpoints trained in the author's [repo](https://github.com/google-research/pegasus) can be
+ found in `convert_pegasus_tf_to_pytorch.py`.
+
+## Usage Example
+
+```python
+>>> from transformers import PegasusForConditionalGeneration, PegasusTokenizer
+>>> import torch
+
+>>> src_text = [
+... """ PG&E stated it scheduled the blackouts in response to forecasts for high winds amid dry conditions. The aim is to reduce the risk of wildfires. Nearly 800 thousand customers were scheduled to be affected by the shutoffs which were expected to last through at least midday tomorrow."""
+... ]
+
+... model_name = "google/pegasus-xsum"
+... device = "cuda" if torch.cuda.is_available() else "cpu"
+... tokenizer = PegasusTokenizer.from_pretrained(model_name)
+... model = PegasusForConditionalGeneration.from_pretrained(model_name).to(device)
+... batch = tokenizer(src_text, truncation=True, padding="longest", return_tensors="pt").to(device)
+... translated = model.generate(**batch)
+... tgt_text = tokenizer.batch_decode(translated, skip_special_tokens=True)
+... assert (
+... tgt_text[0]
+... == "California's largest electricity provider has turned off power to hundreds of thousands of customers."
+... )
+```
+
+## Resources
+
+- [Script](https://github.com/huggingface/transformers/tree/main/examples/research_projects/seq2seq-distillation/finetune_pegasus_xsum.sh) to fine-tune pegasus
+ on the XSUM dataset. Data download instructions at [examples/pytorch/summarization/](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization/README.md).
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## PegasusConfig
+
+[[autodoc]] PegasusConfig
+
+## PegasusTokenizer
+
+warning: `add_tokens` does not work at the moment.
+
+[[autodoc]] PegasusTokenizer
+
+## PegasusTokenizerFast
+
+[[autodoc]] PegasusTokenizerFast
+
+
 +
+ Perceiver IO architecture. Taken from the original paper
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found
+[here](https://github.com/deepmind/deepmind-research/tree/master/perceiver).
+
+
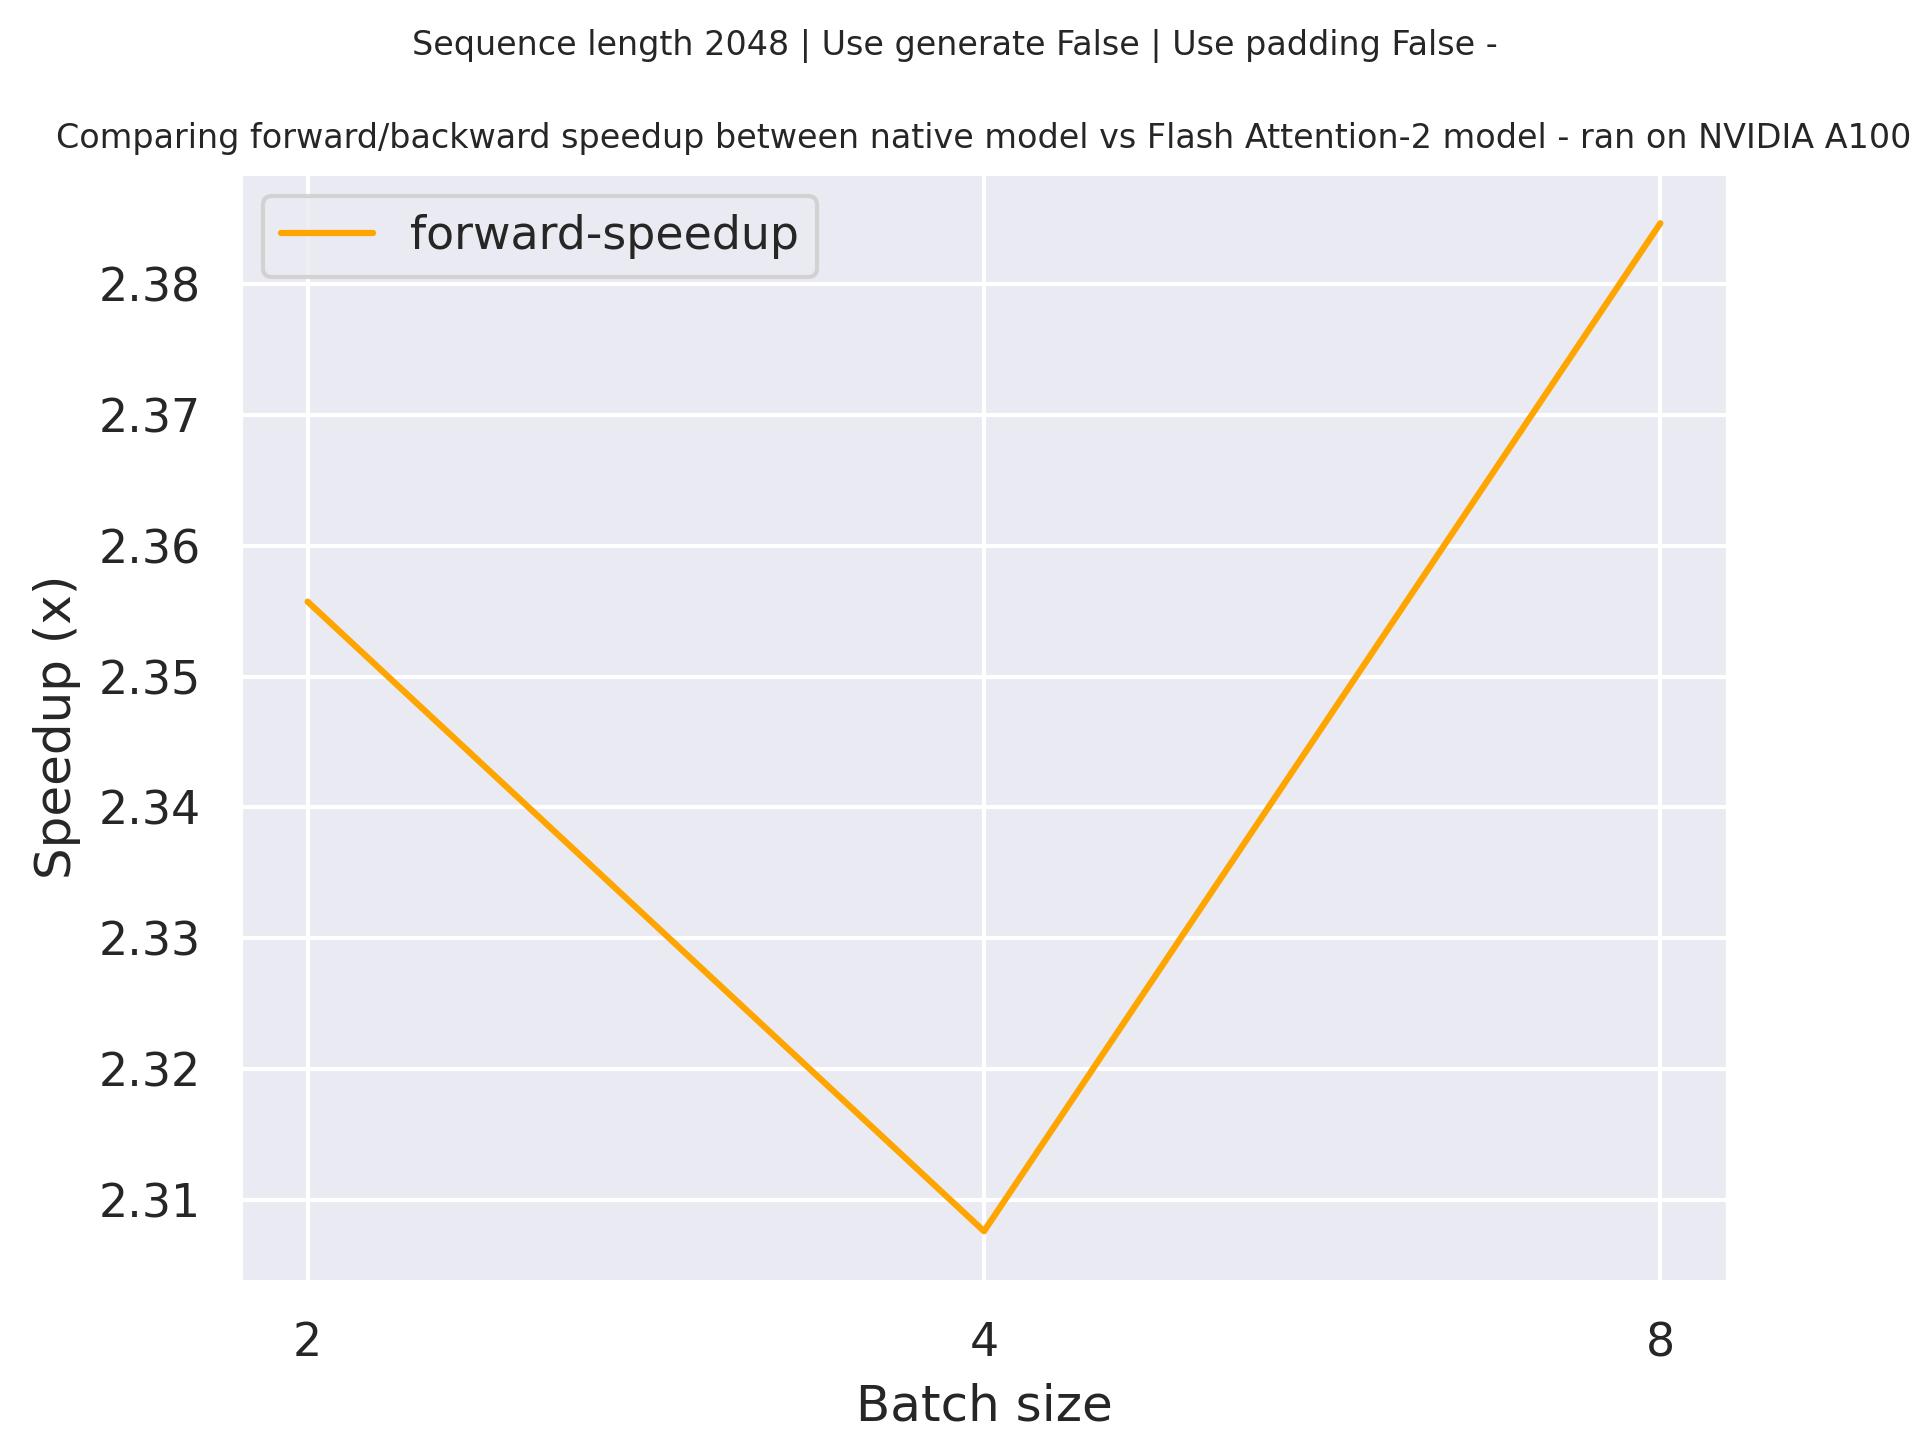 +
 +
+ Pixtral architecture. Taken from the blog post.
+
+Tips:
+
+- Pixtral is a multimodal model, taking images and text as input, and producing text as output.
+- This model follows the [Llava](llava) architecture. The model uses [`PixtralVisionModel`] for its vision encoder, and [`MistralForCausalLM`] for its language decoder.
+- The main contribution is the 2d ROPE (rotary position embeddings) on the images, and support for arbitrary image sizes (the images are not padded together nor are they resized).
+- Similar to [Llava](llava), the model internally replaces the `[IMG]` token placeholders by image embeddings from the vision encoder. The format for one or multiple prompts is the following:
+```
+"
 +
+This model was contributed by [heytanay](https://huggingface.co/heytanay). The original code can be found [here](https://github.com/sail-sg/poolformer).
+
+## Usage tips
+
+- PoolFormer has a hierarchical architecture, where instead of Attention, a simple Average Pooling layer is present. All checkpoints of the model can be found on the [hub](https://huggingface.co/models?other=poolformer).
+- One can use [`PoolFormerImageProcessor`] to prepare images for the model.
+- As most models, PoolFormer comes in different sizes, the details of which can be found in the table below.
+
+| **Model variant** | **Depths** | **Hidden sizes** | **Params (M)** | **ImageNet-1k Top 1** |
+| :---------------: | ------------- | ------------------- | :------------: | :-------------------: |
+| s12 | [2, 2, 6, 2] | [64, 128, 320, 512] | 12 | 77.2 |
+| s24 | [4, 4, 12, 4] | [64, 128, 320, 512] | 21 | 80.3 |
+| s36 | [6, 6, 18, 6] | [64, 128, 320, 512] | 31 | 81.4 |
+| m36 | [6, 6, 18, 6] | [96, 192, 384, 768] | 56 | 82.1 |
+| m48 | [8, 8, 24, 8] | [96, 192, 384, 768] | 73 | 82.5 |
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with PoolFormer.
+
+
 +
+ Qwen2-VL architecture. Taken from the blog post.
+
+This model was contributed by [simonJJJ](https://huggingface.co/simonJJJ).
+
+## Usage example
+
+### Single Media inference
+
+The model can accept both images and videos as input. Here's an example code for inference.
+
+```python
+
+from PIL import Image
+import requests
+import torch
+from torchvision import io
+from typing import Dict
+from transformers import Qwen2VLForConditionalGeneration, AutoTokenizer, AutoProcessor
+
+# Load the model in half-precision on the available device(s)
+model = Qwen2VLForConditionalGeneration.from_pretrained("Qwen/Qwen2-VL-7B-Instruct", device_map="auto")
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-VL-7B-Instruct")
+
+# Image
+url = "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-VL/assets/demo.jpeg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+conversation = [
+ {
+ "role":"user",
+ "content":[
+ {
+ "type":"image",
+ },
+ {
+ "type":"text",
+ "text":"Describe this image."
+ }
+ ]
+ }
+]
+
+
+# Preprocess the inputs
+text_prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+# Excepted output: '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n<|im_start|>user\n<|vision_start|><|image_pad|><|vision_end|>Describe this image.<|im_end|>\n<|im_start|>assistant\n'
+
+inputs = processor(text=[text_prompt], images=[image], padding=True, return_tensors="pt")
+inputs = inputs.to('cuda')
+
+# Inference: Generation of the output
+output_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(inputs.input_ids, output_ids)]
+output_text = processor.batch_decode(generated_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+print(output_text)
+
+# Video
+def fetch_video(ele: Dict, nframe_factor=2):
+ if isinstance(ele['video'], str):
+ def round_by_factor(number: int, factor: int) -> int:
+ return round(number / factor) * factor
+
+ video = ele["video"]
+ if video.startswith("file://"):
+ video = video[7:]
+
+ video, _, info = io.read_video(
+ video,
+ start_pts=ele.get("video_start", 0.0),
+ end_pts=ele.get("video_end", None),
+ pts_unit="sec",
+ output_format="TCHW",
+ )
+ assert not ("fps" in ele and "nframes" in ele), "Only accept either `fps` or `nframes`"
+ if "nframes" in ele:
+ nframes = round_by_factor(ele["nframes"], nframe_factor)
+ else:
+ fps = ele.get("fps", 1.0)
+ nframes = round_by_factor(video.size(0) / info["video_fps"] * fps, nframe_factor)
+ idx = torch.linspace(0, video.size(0) - 1, nframes, dtype=torch.int64)
+ return video[idx]
+
+video_info = {"type": "video", "video": "/path/to/video.mp4", "fps": 1.0}
+video = fetch_video(video_info)
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "video"},
+ {"type": "text", "text": "What happened in the video?"},
+ ],
+ }
+]
+
+# Preprocess the inputs
+text_prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+# Excepted output: '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n<|im_start|>user\n<|vision_start|><|video_pad|><|vision_end|>What happened in the video?<|im_end|>\n<|im_start|>assistant\n'
+
+inputs = processor(text=[text_prompt], videos=[video], padding=True, return_tensors="pt")
+inputs = inputs.to('cuda')
+
+# Inference: Generation of the output
+output_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(inputs.input_ids, output_ids)]
+output_text = processor.batch_decode(generated_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+print(output_text)
+```
+
+### Batch Mixed Media Inference
+
+The model can batch inputs composed of mixed samples of various types such as images, videos, and text. Here is an example.
+
+```python
+image1 = Image.open("/path/to/image1.jpg")
+image2 = Image.open("/path/to/image2.jpg")
+image3 = Image.open("/path/to/image3.jpg")
+image4 = Image.open("/path/to/image4.jpg")
+image5 = Image.open("/path/to/image5.jpg")
+video = fetch_video({
+ "type": "video",
+ "video": "/path/to/video.mp4",
+ "fps": 1.0
+})
+
+# Conversation for the first image
+conversation1 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "Describe this image."}
+ ]
+ }
+]
+
+# Conversation with two images
+conversation2 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "image"},
+ {"type": "text", "text": "What is written in the pictures?"}
+ ]
+ }
+]
+
+# Conversation with pure text
+conversation3 = [
+ {
+ "role": "user",
+ "content": "who are you?"
+ }
+]
+
+
+# Conversation with mixed midia
+conversation4 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "image"},
+ {"type": "video"},
+ {"type": "text", "text": "What are the common elements in these medias?"},
+ ],
+ }
+]
+
+conversations = [conversation1, conversation2, conversation3, conversation4]
+# Preparation for batch inference
+texts = [processor.apply_chat_template(msg, add_generation_prompt=True) for msg in conversations]
+inputs = processor(
+ text=texts,
+ images=[image1, image2, image3, image4, image5],
+ videos=[video],
+ padding=True,
+ return_tensors="pt",
+)
+inputs = inputs.to('cuda')
+
+# Batch Inference
+output_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(inputs.input_ids, output_ids)]
+output_text = processor.batch_decode(generated_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+print(output_text)
+```
+
+### Usage Tips
+
+#### Image Resolution trade-off
+
+The model supports a wide range of resolution inputs. By default, it uses the native resolution for input, but higher resolutions can enhance performance at the cost of more computation. Users can set the minimum and maximum number of pixels to achieve an optimal configuration for their needs.
+
+```python
+min_pixels = 224*224
+max_pixels = 2048*2048
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-VL-7B-Instruct", min_pixels=min_pixels, max_pixels=max_pixels)
+```
+
+In case of limited GPU RAM, one can reduce the resolution as follows:
+
+```python
+min_pixels = 256*28*28
+max_pixels = 1024*28*28
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-VL-7B-Instruct", min_pixels=min_pixels, max_pixels=max_pixels)
+```
+This ensures each image gets encoded using a number between 256-1024 tokens. The 28 comes from the fact that the model uses a patch size of 14 and a temporal patch size of 2 (14 x 2 = 28).
+
+#### Multiple Image Inputs
+
+By default, images and video content are directly included in the conversation. When handling multiple images, it's helpful to add labels to the images and videos for better reference. Users can control this behavior with the following settings:
+
+```python
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "Hello, how are you?"}
+ ]
+ },
+ {
+ "role": "assistant",
+ "content": "I'm doing well, thank you for asking. How can I assist you today?"
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Can you describe these images and video?"},
+ {"type": "image"},
+ {"type": "image"},
+ {"type": "video"},
+ {"type": "text", "text": "These are from my vacation."}
+ ]
+ },
+ {
+ "role": "assistant",
+ "content": "I'd be happy to describe the images and video for you. Could you please provide more context about your vacation?"
+ },
+ {
+ "role": "user",
+ "content": "It was a trip to the mountains. Can you see the details in the images and video?"
+ }
+]
+
+# default:
+prompt_without_id = processor.apply_chat_template(conversation, add_generation_prompt=True)
+# Excepted output: '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n<|im_start|>user\n<|vision_start|><|image_pad|><|vision_end|>Hello, how are you?<|im_end|>\n<|im_start|>assistant\nI'm doing well, thank you for asking. How can I assist you today?<|im_end|>\n<|im_start|>user\nCan you describe these images and video?<|vision_start|><|image_pad|><|vision_end|><|vision_start|><|image_pad|><|vision_end|><|vision_start|><|video_pad|><|vision_end|>These are from my vacation.<|im_end|>\n<|im_start|>assistant\nI'd be happy to describe the images and video for you. Could you please provide more context about your vacation?<|im_end|>\n<|im_start|>user\nIt was a trip to the mountains. Can you see the details in the images and video?<|im_end|>\n<|im_start|>assistant\n'
+
+
+# add ids
+prompt_with_id = processor.apply_chat_template(conversation, add_generation_prompt=True, add_vision_id=True)
+# Excepted output: '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n<|im_start|>user\nPicture 1: <|vision_start|><|image_pad|><|vision_end|>Hello, how are you?<|im_end|>\n<|im_start|>assistant\nI'm doing well, thank you for asking. How can I assist you today?<|im_end|>\n<|im_start|>user\nCan you describe these images and video?Picture 2: <|vision_start|><|image_pad|><|vision_end|>Picture 3: <|vision_start|><|image_pad|><|vision_end|>Video 1: <|vision_start|><|video_pad|><|vision_end|>These are from my vacation.<|im_end|>\n<|im_start|>assistant\nI'd be happy to describe the images and video for you. Could you please provide more context about your vacation?<|im_end|>\n<|im_start|>user\nIt was a trip to the mountains. Can you see the details in the images and video?<|im_end|>\n<|im_start|>assistant\n'
+
+```
+
+#### Flash-Attention 2 to speed up generation
+
+First, make sure to install the latest version of Flash Attention 2:
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Also, you should have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of the [flash attention repository](https://github.com/Dao-AILab/flash-attention). FlashAttention-2 can only be used when a model is loaded in `torch.float16` or `torch.bfloat16`.
+
+To load and run a model using Flash Attention-2, simply add `attn_implementation="flash_attention_2"` when loading the model as follows:
+
+```python
+from transformers import Qwen2VLForConditionalGeneration
+
+model = Qwen2VLForConditionalGeneration.from_pretrained(
+ "Qwen/Qwen2-VL-7B-Instruct",
+ torch_dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+)
+```
+
+## Qwen2VLConfig
+
+[[autodoc]] Qwen2VLConfig
+
+## Qwen2VLImageProcessor
+
+[[autodoc]] Qwen2VLImageProcessor
+ - preprocess
+
+## Qwen2VLProcessor
+
+[[autodoc]] Qwen2VLProcessor
+
+## Qwen2VLModel
+
+[[autodoc]] Qwen2VLModel
+ - forward
+
+## Qwen2VLForConditionalGeneration
+
+[[autodoc]] Qwen2VLForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/rag.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/rag.md
new file mode 100644
index 0000000000000000000000000000000000000000..1891efe742639e212c431a585aaa09326e39fc91
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/rag.md
@@ -0,0 +1,121 @@
+
+
+# RAG
+
+
 +
+
 +
+This model was contributed by [Francesco](https://huggingface.co/Francesco). The TensorFlow version of this model was added by [amyeroberts](https://huggingface.co/amyeroberts). The original code can be found [here](https://github.com/KaimingHe/deep-residual-networks).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with ResNet.
+
+
 +
+ RT-DETR performance relative to YOLO models. Taken from the original paper.
+
+The model version was contributed by [rafaelpadilla](https://huggingface.co/rafaelpadilla) and [sangbumchoi](https://github.com/SangbumChoi). The original code can be found [here](https://github.com/lyuwenyu/RT-DETR/).
+
+
+## Usage tips
+
+Initially, an image is processed using a pre-trained convolutional neural network, specifically a Resnet-D variant as referenced in the original code. This network extracts features from the final three layers of the architecture. Following this, a hybrid encoder is employed to convert the multi-scale features into a sequential array of image features. Then, a decoder, equipped with auxiliary prediction heads is used to refine the object queries. This process facilitates the direct generation of bounding boxes, eliminating the need for any additional post-processing to acquire the logits and coordinates for the bounding boxes.
+
+```py
+>>> import torch
+>>> import requests
+
+>>> from PIL import Image
+>>> from transformers import RTDetrForObjectDetection, RTDetrImageProcessor
+
+>>> url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> image_processor = RTDetrImageProcessor.from_pretrained("PekingU/rtdetr_r50vd")
+>>> model = RTDetrForObjectDetection.from_pretrained("PekingU/rtdetr_r50vd")
+
+>>> inputs = image_processor(images=image, return_tensors="pt")
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> results = image_processor.post_process_object_detection(outputs, target_sizes=torch.tensor([(image.height, image.width)]), threshold=0.3)
+
+>>> for result in results:
+... for score, label_id, box in zip(result["scores"], result["labels"], result["boxes"]):
+... score, label = score.item(), label_id.item()
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"{model.config.id2label[label]}: {score:.2f} {box}")
+sofa: 0.97 [0.14, 0.38, 640.13, 476.21]
+cat: 0.96 [343.38, 24.28, 640.14, 371.5]
+cat: 0.96 [13.23, 54.18, 318.98, 472.22]
+remote: 0.95 [40.11, 73.44, 175.96, 118.48]
+remote: 0.92 [333.73, 76.58, 369.97, 186.99]
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with RT-DETR.
+
+
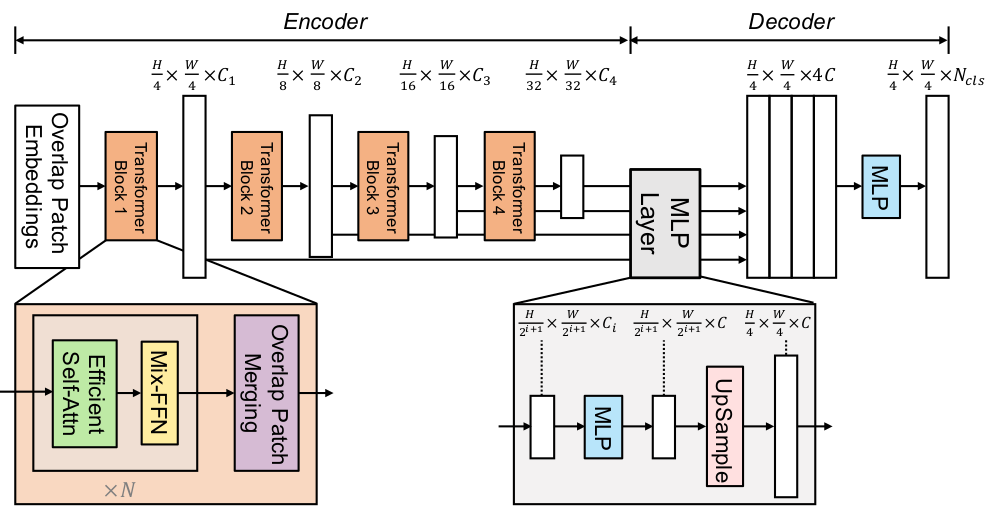 +
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The TensorFlow version
+of the model was contributed by [sayakpaul](https://huggingface.co/sayakpaul). The original code can be found [here](https://github.com/NVlabs/SegFormer).
+
+## Usage tips
+
+- SegFormer consists of a hierarchical Transformer encoder, and a lightweight all-MLP decoder head.
+ [`SegformerModel`] is the hierarchical Transformer encoder (which in the paper is also referred to
+ as Mix Transformer or MiT). [`SegformerForSemanticSegmentation`] adds the all-MLP decoder head on
+ top to perform semantic segmentation of images. In addition, there's
+ [`SegformerForImageClassification`] which can be used to - you guessed it - classify images. The
+ authors of SegFormer first pre-trained the Transformer encoder on ImageNet-1k to classify images. Next, they throw
+ away the classification head, and replace it by the all-MLP decode head. Next, they fine-tune the model altogether on
+ ADE20K, Cityscapes and COCO-stuff, which are important benchmarks for semantic segmentation. All checkpoints can be
+ found on the [hub](https://huggingface.co/models?other=segformer).
+- The quickest way to get started with SegFormer is by checking the [example notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/SegFormer) (which showcase both inference and
+ fine-tuning on custom data). One can also check out the [blog post](https://huggingface.co/blog/fine-tune-segformer) introducing SegFormer and illustrating how it can be fine-tuned on custom data.
+- TensorFlow users should refer to [this repository](https://github.com/deep-diver/segformer-tf-transformers) that shows off-the-shelf inference and fine-tuning.
+- One can also check out [this interactive demo on Hugging Face Spaces](https://huggingface.co/spaces/chansung/segformer-tf-transformers)
+ to try out a SegFormer model on custom images.
+- SegFormer works on any input size, as it pads the input to be divisible by `config.patch_sizes`.
+- One can use [`SegformerImageProcessor`] to prepare images and corresponding segmentation maps
+ for the model. Note that this image processor is fairly basic and does not include all data augmentations used in
+ the original paper. The original preprocessing pipelines (for the ADE20k dataset for instance) can be found [here](https://github.com/NVlabs/SegFormer/blob/master/local_configs/_base_/datasets/ade20k_repeat.py). The most
+ important preprocessing step is that images and segmentation maps are randomly cropped and padded to the same size,
+ such as 512x512 or 640x640, after which they are normalized.
+- One additional thing to keep in mind is that one can initialize [`SegformerImageProcessor`] with
+ `do_reduce_labels` set to `True` or `False`. In some datasets (like ADE20k), the 0 index is used in the annotated
+ segmentation maps for background. However, ADE20k doesn't include the "background" class in its 150 labels.
+ Therefore, `do_reduce_labels` is used to reduce all labels by 1, and to make sure no loss is computed for the
+ background class (i.e. it replaces 0 in the annotated maps by 255, which is the *ignore_index* of the loss function
+ used by [`SegformerForSemanticSegmentation`]). However, other datasets use the 0 index as
+ background class and include this class as part of all labels. In that case, `do_reduce_labels` should be set to
+ `False`, as loss should also be computed for the background class.
+- As most models, SegFormer comes in different sizes, the details of which can be found in the table below
+ (taken from Table 7 of the [original paper](https://arxiv.org/abs/2105.15203)).
+
+| **Model variant** | **Depths** | **Hidden sizes** | **Decoder hidden size** | **Params (M)** | **ImageNet-1k Top 1** |
+| :---------------: | ------------- | ------------------- | :---------------------: | :------------: | :-------------------: |
+| MiT-b0 | [2, 2, 2, 2] | [32, 64, 160, 256] | 256 | 3.7 | 70.5 |
+| MiT-b1 | [2, 2, 2, 2] | [64, 128, 320, 512] | 256 | 14.0 | 78.7 |
+| MiT-b2 | [3, 4, 6, 3] | [64, 128, 320, 512] | 768 | 25.4 | 81.6 |
+| MiT-b3 | [3, 4, 18, 3] | [64, 128, 320, 512] | 768 | 45.2 | 83.1 |
+| MiT-b4 | [3, 8, 27, 3] | [64, 128, 320, 512] | 768 | 62.6 | 83.6 |
+| MiT-b5 | [3, 6, 40, 3] | [64, 128, 320, 512] | 768 | 82.0 | 83.8 |
+
+Note that MiT in the above table refers to the Mix Transformer encoder backbone introduced in SegFormer. For
+SegFormer's results on the segmentation datasets like ADE20k, refer to the [paper](https://arxiv.org/abs/2105.15203).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with SegFormer.
+
+
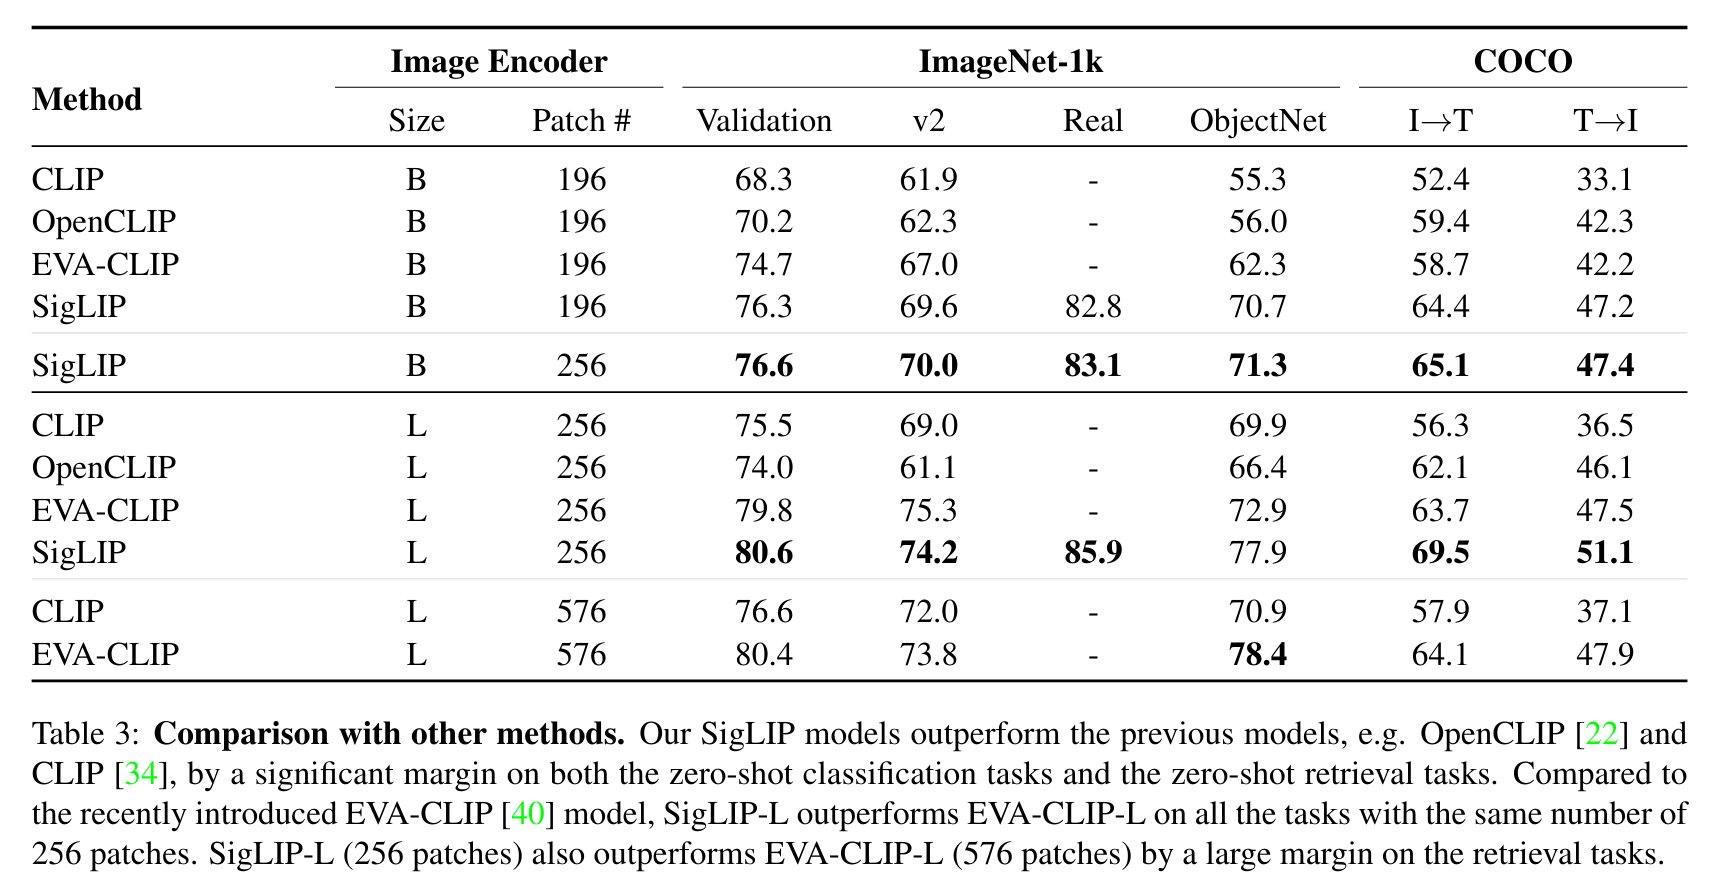 +
+ SigLIP evaluation results compared to CLIP. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/google-research/big_vision/tree/main).
+
+## Usage example
+
+There are 2 main ways to use SigLIP: either using the pipeline API, which abstracts away all the complexity for you, or by using the `SiglipModel` class yourself.
+
+### Pipeline API
+
+The pipeline allows to use the model in a few lines of code:
+
+```python
+>>> from transformers import pipeline
+>>> from PIL import Image
+>>> import requests
+
+>>> # load pipe
+>>> image_classifier = pipeline(task="zero-shot-image-classification", model="google/siglip-base-patch16-224")
+
+>>> # load image
+>>> url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> # inference
+>>> candidate_labels = ["2 cats", "a plane", "a remote"]
+>>> outputs = image_classifier(image, candidate_labels=candidate_labels)
+>>> outputs = [{"score": round(output["score"], 4), "label": output["label"] } for output in outputs]
+>>> print(outputs)
+[{'score': 0.1979, 'label': '2 cats'}, {'score': 0.0, 'label': 'a remote'}, {'score': 0.0, 'label': 'a plane'}]
+```
+
+### Using the model yourself
+
+If you want to do the pre- and postprocessing yourself, here's how to do that:
+
+```python
+>>> from PIL import Image
+>>> import requests
+>>> from transformers import AutoProcessor, AutoModel
+>>> import torch
+
+>>> model = AutoModel.from_pretrained("google/siglip-base-patch16-224")
+>>> processor = AutoProcessor.from_pretrained("google/siglip-base-patch16-224")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> candidate_labels = ["2 cats", "2 dogs"]
+# follows the pipeline prompt template to get same results
+>>> texts = [f'This is a photo of {label}.' for label in candidate_labels]
+>>> # important: we pass `padding=max_length` since the model was trained with this
+>>> inputs = processor(text=texts, images=image, padding="max_length", return_tensors="pt")
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> logits_per_image = outputs.logits_per_image
+>>> probs = torch.sigmoid(logits_per_image) # these are the probabilities
+>>> print(f"{probs[0][0]:.1%} that image 0 is '{candidate_labels[0]}'")
+31.9% that image 0 is 'a photo of 2 cats'
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with SigLIP.
+
+- [Zero-shot image classification task guide](../tasks/zero_shot_image_classification_md)
+- Demo notebooks for SigLIP can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/SigLIP). 🌎
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+## Combining SigLIP and Flash Attention 2
+
+First, make sure to install the latest version of Flash Attention 2.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Make also sure that you have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of flash-attn repository. Make also sure to load your model in half-precision (e.g. `torch.float16``)
+
+To load and run a model using Flash Attention 2, refer to the snippet below:
+
+```python
+>>> import torch
+>>> import requests
+>>> from PIL import Image
+>>> from transformers import SiglipProcessor, SiglipModel
+>>> device = "cuda" # the device to load the model onto
+
+>>> model = SiglipModel.from_pretrained(
+... "google/siglip-so400m-patch14-384",
+... attn_implementation="flash_attention_2",
+... torch_dtype=torch.float16,
+... device_map=device,
+... )
+>>> processor = SiglipProcessor.from_pretrained("google/siglip-so400m-patch14-384")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> candidate_labels = ["2 cats", "2 dogs"]
+# follows the pipeline prompt template to get same results
+>>> texts = [f'This is a photo of {label}.' for label in candidate_labels]
+# important: we pass `padding=max_length` since the model was trained with this
+>>> inputs = processor(text=texts, images=image, padding="max_length", return_tensors="pt")
+>>> inputs.to(device)
+
+>>> with torch.no_grad():
+... with torch.autocast(device):
+... outputs = model(**inputs)
+
+>>> logits_per_image = outputs.logits_per_image
+>>> probs = torch.sigmoid(logits_per_image) # these are the probabilities
+>>> print(f"{probs[0][0]:.1%} that image 0 is '{candidate_labels[0]}'")
+51.3% that image 0 is 'This is a photo of 2 cats.'
+```
+
+
+## Using Scaled Dot Product Attention (SDPA)
+
+PyTorch includes a native scaled dot-product attention (SDPA) operator as part of `torch.nn.functional`. This function
+encompasses several implementations that can be applied depending on the inputs and the hardware in use. See the
+[official documentation](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)
+or the [GPU Inference](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)
+page for more information.
+
+You may set `attn_implementation="sdpa"` in `from_pretrained()` to explicitly request SDPA to be used. Make sure you have `torch>=2.1.1`.
+
+```python
+>>> from transformers import SiglipModel
+
+>>> model = SiglipModel.from_pretrained(
+... "google/siglip-so400m-patch14-384",
+... attn_implementation="sdpa",
+... torch_dtype=torch.float16,
+... device_map=device,
+... )
+```
+
+For the best speedups, we recommend loading the model in half-precision (e.g. `torch.float16` or `torch.bfloat16`).
+
+
+## Expected speedups
+
+Below is an expected speedup diagram that compares inference time between the native implementation in transformers using `google/siglip-so400m-patch14-384` checkpoint in `float16` precision and the Flash Attention 2 / SDPA version of the model using different batch sizes.
+
+
 +
 +
+ SuperPoint overview. Taken from the original paper.
+
+## Usage tips
+
+Here is a quick example of using the model to detect interest points in an image:
+
+```python
+from transformers import AutoImageProcessor, SuperPointForKeypointDetection
+import torch
+from PIL import Image
+import requests
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+processor = AutoImageProcessor.from_pretrained("magic-leap-community/superpoint")
+model = SuperPointForKeypointDetection.from_pretrained("magic-leap-community/superpoint")
+
+inputs = processor(image, return_tensors="pt")
+outputs = model(**inputs)
+```
+
+The outputs contain the list of keypoint coordinates with their respective score and description (a 256-long vector).
+
+You can also feed multiple images to the model. Due to the nature of SuperPoint, to output a dynamic number of keypoints,
+you will need to use the mask attribute to retrieve the respective information :
+
+```python
+from transformers import AutoImageProcessor, SuperPointForKeypointDetection
+import torch
+from PIL import Image
+import requests
+
+url_image_1 = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image_1 = Image.open(requests.get(url_image_1, stream=True).raw)
+url_image_2 = "http://images.cocodataset.org/test-stuff2017/000000000568.jpg"
+image_2 = Image.open(requests.get(url_image_2, stream=True).raw)
+
+images = [image_1, image_2]
+
+processor = AutoImageProcessor.from_pretrained("magic-leap-community/superpoint")
+model = SuperPointForKeypointDetection.from_pretrained("magic-leap-community/superpoint")
+
+inputs = processor(images, return_tensors="pt")
+outputs = model(**inputs)
+image_sizes = [(image.height, image.width) for image in images]
+outputs = processor.post_process_keypoint_detection(outputs, image_sizes)
+
+for output in outputs:
+ for keypoints, scores, descriptors in zip(output["keypoints"], output["scores"], output["descriptors"]):
+ print(f"Keypoints: {keypoints}")
+ print(f"Scores: {scores}")
+ print(f"Descriptors: {descriptors}")
+```
+
+You can then print the keypoints on the image of your choice to visualize the result:
+```python
+import matplotlib.pyplot as plt
+
+plt.axis("off")
+plt.imshow(image_1)
+plt.scatter(
+ outputs[0]["keypoints"][:, 0],
+ outputs[0]["keypoints"][:, 1],
+ c=outputs[0]["scores"] * 100,
+ s=outputs[0]["scores"] * 50,
+ alpha=0.8
+)
+plt.savefig(f"output_image.png")
+```
+
+
+This model was contributed by [stevenbucaille](https://huggingface.co/stevenbucaille).
+The original code can be found [here](https://github.com/magicleap/SuperPointPretrainedNetwork).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with SuperPoint. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- A notebook showcasing inference and visualization with SuperPoint can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/SuperPoint/Inference_with_SuperPoint_to_detect_interest_points_in_an_image.ipynb). 🌎
+
+## SuperPointConfig
+
+[[autodoc]] SuperPointConfig
+
+## SuperPointImageProcessor
+
+[[autodoc]] SuperPointImageProcessor
+
+- preprocess
+- post_process_keypoint_detection
+
+## SuperPointForKeypointDetection
+
+[[autodoc]] SuperPointForKeypointDetection
+
+- forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swiftformer.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swiftformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..319c79fce4fbece5b557dd0f03d688174fbf5043
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swiftformer.md
@@ -0,0 +1,54 @@
+
+
+# SwiftFormer
+
+## Overview
+
+The SwiftFormer model was proposed in [SwiftFormer: Efficient Additive Attention for Transformer-based Real-time Mobile Vision Applications](https://arxiv.org/abs/2303.15446) by Abdelrahman Shaker, Muhammad Maaz, Hanoona Rasheed, Salman Khan, Ming-Hsuan Yang, Fahad Shahbaz Khan.
+
+The SwiftFormer paper introduces a novel efficient additive attention mechanism that effectively replaces the quadratic matrix multiplication operations in the self-attention computation with linear element-wise multiplications. A series of models called 'SwiftFormer' is built based on this, which achieves state-of-the-art performance in terms of both accuracy and mobile inference speed. Even their small variant achieves 78.5% top-1 ImageNet1K accuracy with only 0.8 ms latency on iPhone 14, which is more accurate and 2× faster compared to MobileViT-v2.
+
+The abstract from the paper is the following:
+
+*Self-attention has become a defacto choice for capturing global context in various vision applications. However, its quadratic computational complexity with respect to image resolution limits its use in real-time applications, especially for deployment on resource-constrained mobile devices. Although hybrid approaches have been proposed to combine the advantages of convolutions and self-attention for a better speed-accuracy trade-off, the expensive matrix multiplication operations in self-attention remain a bottleneck. In this work, we introduce a novel efficient additive attention mechanism that effectively replaces the quadratic matrix multiplication operations with linear element-wise multiplications. Our design shows that the key-value interaction can be replaced with a linear layer without sacrificing any accuracy. Unlike previous state-of-the-art methods, our efficient formulation of self-attention enables its usage at all stages of the network. Using our proposed efficient additive attention, we build a series of models called "SwiftFormer" which achieves state-of-the-art performance in terms of both accuracy and mobile inference speed. Our small variant achieves 78.5% top-1 ImageNet-1K accuracy with only 0.8 ms latency on iPhone 14, which is more accurate and 2x faster compared to MobileViT-v2.*
+
+This model was contributed by [shehan97](https://huggingface.co/shehan97). The TensorFlow version was contributed by [joaocmd](https://huggingface.co/joaocmd).
+The original code can be found [here](https://github.com/Amshaker/SwiftFormer).
+
+## SwiftFormerConfig
+
+[[autodoc]] SwiftFormerConfig
+
+## SwiftFormerModel
+
+[[autodoc]] SwiftFormerModel
+ - forward
+
+## SwiftFormerForImageClassification
+
+[[autodoc]] SwiftFormerForImageClassification
+ - forward
+
+## TFSwiftFormerModel
+
+[[autodoc]] TFSwiftFormerModel
+ - call
+
+## TFSwiftFormerForImageClassification
+
+[[autodoc]] TFSwiftFormerForImageClassification
+ - call
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swin.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swin.md
new file mode 100644
index 0000000000000000000000000000000000000000..e23c882a3f097aef0bcc3e04469ed0a3104be982
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swin.md
@@ -0,0 +1,107 @@
+
+
+# Swin Transformer
+
+## Overview
+
+The Swin Transformer was proposed in [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030)
+by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
+
+The abstract from the paper is the following:
+
+*This paper presents a new vision Transformer, called Swin Transformer, that capably serves as a general-purpose backbone
+for computer vision. Challenges in adapting Transformer from language to vision arise from differences between the two domains,
+such as large variations in the scale of visual entities and the high resolution of pixels in images compared to words in text.
+To address these differences, we propose a hierarchical Transformer whose representation is computed with \bold{S}hifted
+\bold{win}dows. The shifted windowing scheme brings greater efficiency by limiting self-attention computation to non-overlapping
+local windows while also allowing for cross-window connection. This hierarchical architecture has the flexibility to model at
+various scales and has linear computational complexity with respect to image size. These qualities of Swin Transformer make it
+compatible with a broad range of vision tasks, including image classification (87.3 top-1 accuracy on ImageNet-1K) and dense
+prediction tasks such as object detection (58.7 box AP and 51.1 mask AP on COCO test-dev) and semantic segmentation
+(53.5 mIoU on ADE20K val). Its performance surpasses the previous state-of-the-art by a large margin of +2.7 box AP and
++2.6 mask AP on COCO, and +3.2 mIoU on ADE20K, demonstrating the potential of Transformer-based models as vision backbones.
+The hierarchical design and the shifted window approach also prove beneficial for all-MLP architectures.*
+
+
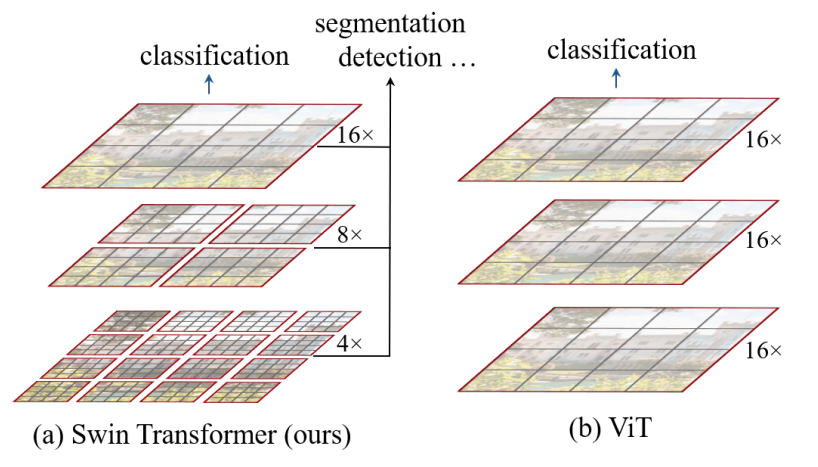 +
+ Swin Transformer architecture. Taken from the original paper.
+
+This model was contributed by [novice03](https://huggingface.co/novice03). The Tensorflow version of this model was contributed by [amyeroberts](https://huggingface.co/amyeroberts). The original code can be found [here](https://github.com/microsoft/Swin-Transformer).
+
+## Usage tips
+
+- Swin pads the inputs supporting any input height and width (if divisible by `32`).
+- Swin can be used as a *backbone*. When `output_hidden_states = True`, it will output both `hidden_states` and `reshaped_hidden_states`. The `reshaped_hidden_states` have a shape of `(batch, num_channels, height, width)` rather than `(batch_size, sequence_length, num_channels)`.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Swin Transformer.
+
+
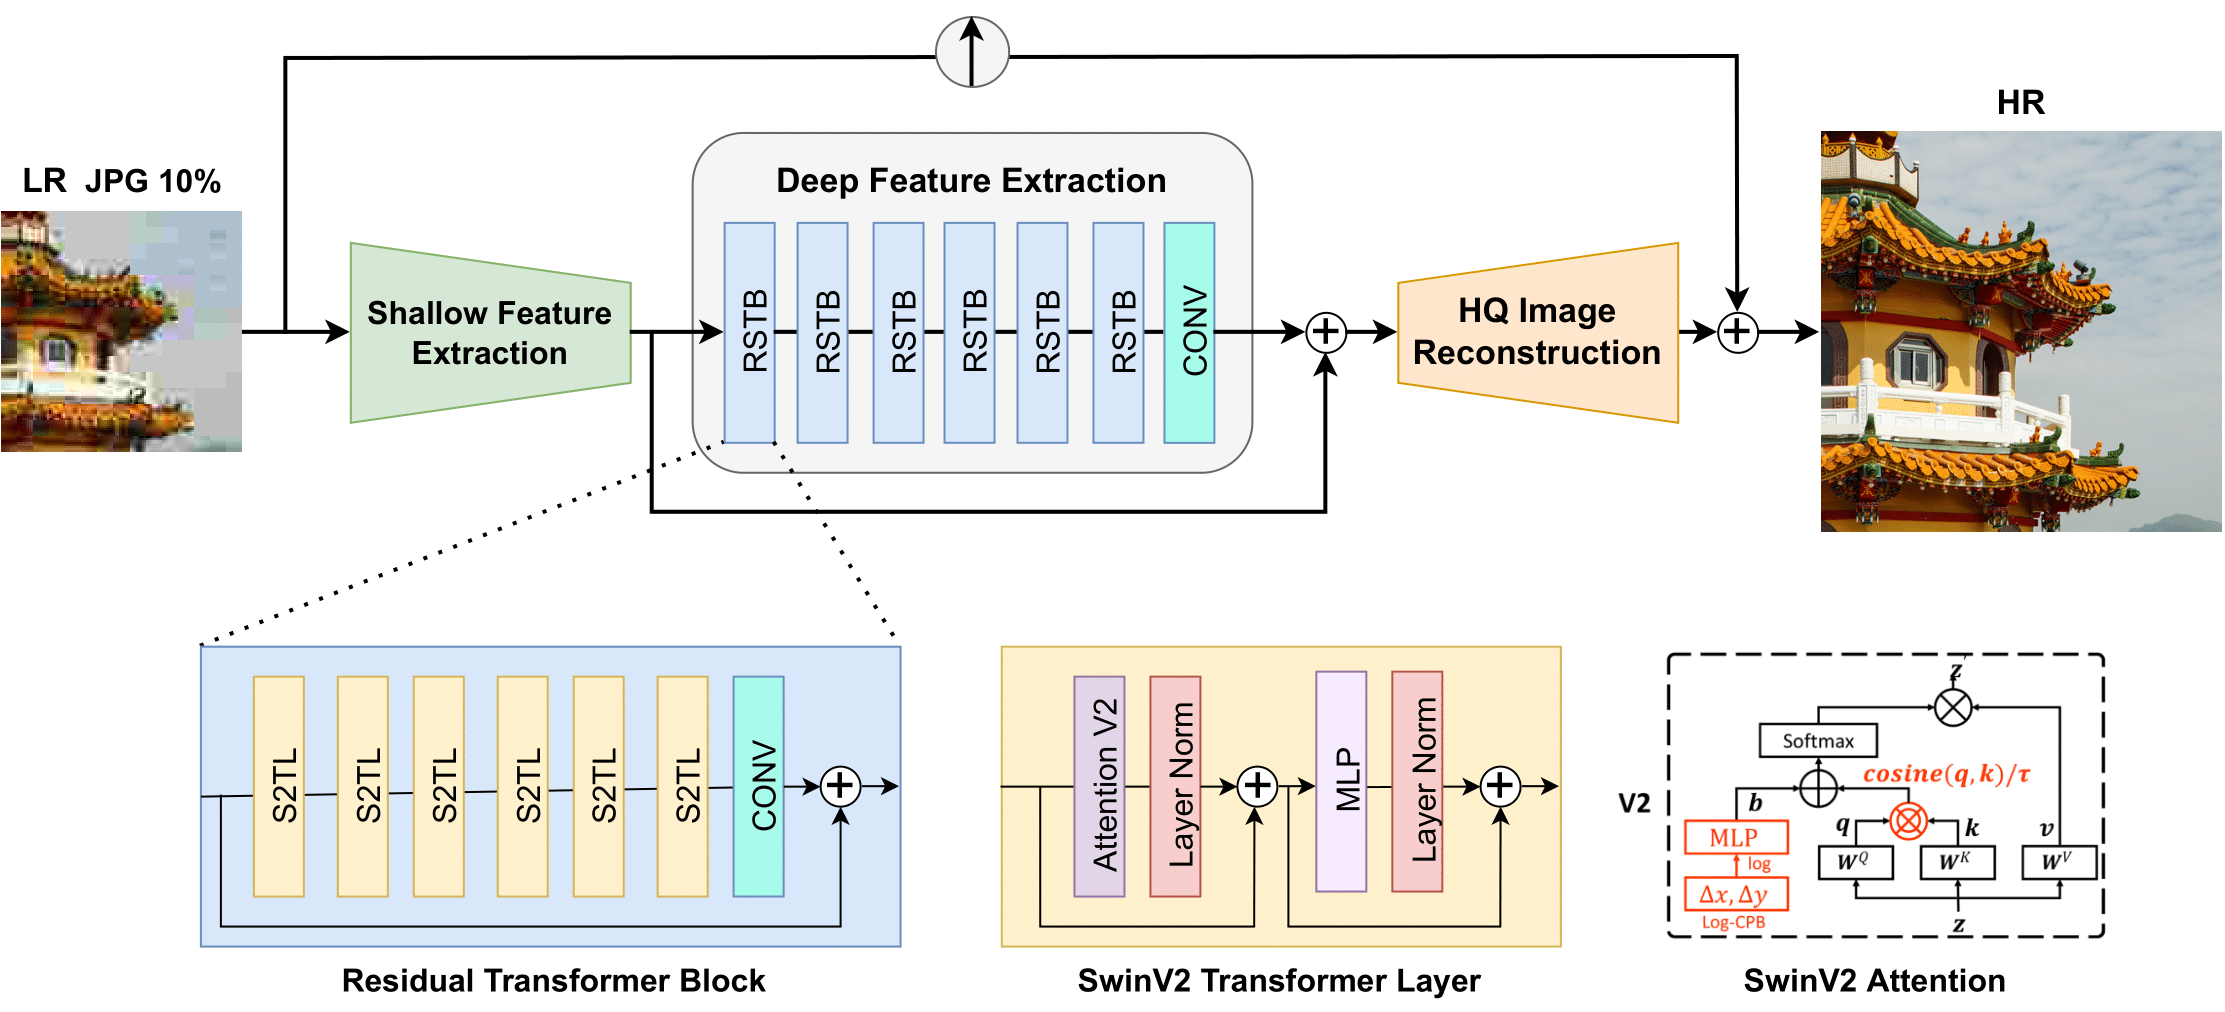 +
+ Swin2SR architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/mv-lab/swin2sr).
+
+## Resources
+
+Demo notebooks for Swin2SR can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Swin2SR).
+
+A demo Space for image super-resolution with SwinSR can be found [here](https://huggingface.co/spaces/jjourney1125/swin2sr).
+
+## Swin2SRImageProcessor
+
+[[autodoc]] Swin2SRImageProcessor
+ - preprocess
+
+## Swin2SRConfig
+
+[[autodoc]] Swin2SRConfig
+
+## Swin2SRModel
+
+[[autodoc]] Swin2SRModel
+ - forward
+
+## Swin2SRForImageSuperResolution
+
+[[autodoc]] Swin2SRForImageSuperResolution
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swinv2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swinv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..25233dca33954554c92f177fe076a779e99f0be6
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/swinv2.md
@@ -0,0 +1,62 @@
+
+
+# Swin Transformer V2
+
+## Overview
+
+The Swin Transformer V2 model was proposed in [Swin Transformer V2: Scaling Up Capacity and Resolution](https://arxiv.org/abs/2111.09883) by Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo.
+
+The abstract from the paper is the following:
+
+*Large-scale NLP models have been shown to significantly improve the performance on language tasks with no signs of saturation. They also demonstrate amazing few-shot capabilities like that of human beings. This paper aims to explore large-scale models in computer vision. We tackle three major issues in training and application of large vision models, including training instability, resolution gaps between pre-training and fine-tuning, and hunger on labelled data. Three main techniques are proposed: 1) a residual-post-norm method combined with cosine attention to improve training stability; 2) A log-spaced continuous position bias method to effectively transfer models pre-trained using low-resolution images to downstream tasks with high-resolution inputs; 3) A self-supervised pre-training method, SimMIM, to reduce the needs of vast labeled images. Through these techniques, this paper successfully trained a 3 billion-parameter Swin Transformer V2 model, which is the largest dense vision model to date, and makes it capable of training with images of up to 1,536×1,536 resolution. It set new performance records on 4 representative vision tasks, including ImageNet-V2 image classification, COCO object detection, ADE20K semantic segmentation, and Kinetics-400 video action classification. Also note our training is much more efficient than that in Google's billion-level visual models, which consumes 40 times less labelled data and 40 times less training time.*
+
+This model was contributed by [nandwalritik](https://huggingface.co/nandwalritik).
+The original code can be found [here](https://github.com/microsoft/Swin-Transformer).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Swin Transformer v2.
+
+
 +
+ Table detection and table structure recognition clarified. Taken from the original paper.
+
+The authors released 2 models, one for [table detection](https://huggingface.co/microsoft/table-transformer-detection) in
+documents, one for [table structure recognition](https://huggingface.co/microsoft/table-transformer-structure-recognition)
+(the task of recognizing the individual rows, columns etc. in a table).
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be
+found [here](https://github.com/microsoft/table-transformer).
+
+## Resources
+
+
 +
+ TAPAS architecture. Taken from the original blog post.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The Tensorflow version of this model was contributed by [kamalkraj](https://huggingface.co/kamalkraj). The original code can be found [here](https://github.com/google-research/tapas).
+
+## Usage tips
+
+- TAPAS is a model that uses relative position embeddings by default (restarting the position embeddings at every cell of the table). Note that this is something that was added after the publication of the original TAPAS paper. According to the authors, this usually results in a slightly better performance, and allows you to encode longer sequences without running out of embeddings. This is reflected in the `reset_position_index_per_cell` parameter of [`TapasConfig`], which is set to `True` by default. The default versions of the models available on the [hub](https://huggingface.co/models?search=tapas) all use relative position embeddings. You can still use the ones with absolute position embeddings by passing in an additional argument `revision="no_reset"` when calling the `from_pretrained()` method. Note that it's usually advised to pad the inputs on the right rather than the left.
+- TAPAS is based on BERT, so `TAPAS-base` for example corresponds to a `BERT-base` architecture. Of course, `TAPAS-large` will result in the best performance (the results reported in the paper are from `TAPAS-large`). Results of the various sized models are shown on the [original GitHub repository](https://github.com/google-research/tapas).
+- TAPAS has checkpoints fine-tuned on SQA, which are capable of answering questions related to a table in a conversational set-up. This means that you can ask follow-up questions such as "what is his age?" related to the previous question. Note that the forward pass of TAPAS is a bit different in case of a conversational set-up: in that case, you have to feed every table-question pair one by one to the model, such that the `prev_labels` token type ids can be overwritten by the predicted `labels` of the model to the previous question. See "Usage" section for more info.
+- TAPAS is similar to BERT and therefore relies on the masked language modeling (MLM) objective. It is therefore efficient at predicting masked tokens and at NLU in general, but is not optimal for text generation. Models trained with a causal language modeling (CLM) objective are better in that regard. Note that TAPAS can be used as an encoder in the EncoderDecoderModel framework, to combine it with an autoregressive text decoder such as GPT-2.
+
+## Usage: fine-tuning
+
+Here we explain how you can fine-tune [`TapasForQuestionAnswering`] on your own dataset.
+
+**STEP 1: Choose one of the 3 ways in which you can use TAPAS - or experiment**
+
+Basically, there are 3 different ways in which one can fine-tune [`TapasForQuestionAnswering`], corresponding to the different datasets on which Tapas was fine-tuned:
+
+1. SQA: if you're interested in asking follow-up questions related to a table, in a conversational set-up. For example if you first ask "what's the name of the first actor?" then you can ask a follow-up question such as "how old is he?". Here, questions do not involve any aggregation (all questions are cell selection questions).
+2. WTQ: if you're not interested in asking questions in a conversational set-up, but rather just asking questions related to a table, which might involve aggregation, such as counting a number of rows, summing up cell values or averaging cell values. You can then for example ask "what's the total number of goals Cristiano Ronaldo made in his career?". This case is also called **weak supervision**, since the model itself must learn the appropriate aggregation operator (SUM/COUNT/AVERAGE/NONE) given only the answer to the question as supervision.
+3. WikiSQL-supervised: this dataset is based on WikiSQL with the model being given the ground truth aggregation operator during training. This is also called **strong supervision**. Here, learning the appropriate aggregation operator is much easier.
+
+To summarize:
+
+| **Task** | **Example dataset** | **Description** |
+|-------------------------------------|---------------------|---------------------------------------------------------------------------------------------------------|
+| Conversational | SQA | Conversational, only cell selection questions |
+| Weak supervision for aggregation | WTQ | Questions might involve aggregation, and the model must learn this given only the answer as supervision |
+| Strong supervision for aggregation | WikiSQL-supervised | Questions might involve aggregation, and the model must learn this given the gold aggregation operator |
+
+
 +
+ TrOCR architecture. Taken from the original paper.
+
+Please refer to the [`VisionEncoderDecoder`] class on how to use this model.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found
+[here](https://github.com/microsoft/unilm/tree/6f60612e7cc86a2a1ae85c47231507a587ab4e01/trocr).
+
+## Usage tips
+
+- The quickest way to get started with TrOCR is by checking the [tutorial
+ notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/TrOCR), which show how to use the model
+ at inference time as well as fine-tuning on custom data.
+- TrOCR is pre-trained in 2 stages before being fine-tuned on downstream datasets. It achieves state-of-the-art results
+ on both printed (e.g. the [SROIE dataset](https://paperswithcode.com/dataset/sroie) and handwritten (e.g. the [IAM
+ Handwriting dataset](https://fki.tic.heia-fr.ch/databases/iam-handwriting-database>) text recognition tasks. For more
+ information, see the [official models](https://huggingface.co/models?other=trocr>).
+- TrOCR is always used within the [VisionEncoderDecoder](vision-encoder-decoder) framework.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with TrOCR. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
 +
 +
+ TVP architecture. Taken from the original paper.
+
+This model was contributed by [Jiqing Feng](https://huggingface.co/Jiqing). The original code can be found [here](https://github.com/intel/TVP).
+
+## Usage tips and examples
+
+Prompts are optimized perturbation patterns, which would be added to input video frames or text features. Universal set refers to using the same exact set of prompts for any input, this means that these prompts are added consistently to all video frames and text features, regardless of the input's content.
+
+TVP consists of a visual encoder and cross-modal encoder. A universal set of visual prompts and text prompts to be integrated into sampled video frames and textual features, respectively. Specially, a set of different visual prompts are applied to uniformly-sampled frames of one untrimmed video in order.
+
+The goal of this model is to incorporate trainable prompts into both visual inputs and textual features to temporal video grounding(TVG) problems.
+In principle, one can apply any visual, cross-modal encoder in the proposed architecture.
+
+The [`TvpProcessor`] wraps [`BertTokenizer`] and [`TvpImageProcessor`] into a single instance to both
+encode the text and prepare the images respectively.
+
+The following example shows how to run temporal video grounding using [`TvpProcessor`] and [`TvpForVideoGrounding`].
+```python
+import av
+import cv2
+import numpy as np
+import torch
+from huggingface_hub import hf_hub_download
+from transformers import AutoProcessor, TvpForVideoGrounding
+
+
+def pyav_decode(container, sampling_rate, num_frames, clip_idx, num_clips, target_fps):
+ '''
+ Convert the video from its original fps to the target_fps and decode the video with PyAV decoder.
+ Args:
+ container (container): pyav container.
+ sampling_rate (int): frame sampling rate (interval between two sampled frames).
+ num_frames (int): number of frames to sample.
+ clip_idx (int): if clip_idx is -1, perform random temporal sampling.
+ If clip_idx is larger than -1, uniformly split the video to num_clips
+ clips, and select the clip_idx-th video clip.
+ num_clips (int): overall number of clips to uniformly sample from the given video.
+ target_fps (int): the input video may have different fps, convert it to
+ the target video fps before frame sampling.
+ Returns:
+ frames (tensor): decoded frames from the video. Return None if the no
+ video stream was found.
+ fps (float): the number of frames per second of the video.
+ '''
+ video = container.streams.video[0]
+ fps = float(video.average_rate)
+ clip_size = sampling_rate * num_frames / target_fps * fps
+ delta = max(num_frames - clip_size, 0)
+ start_idx = delta * clip_idx / num_clips
+ end_idx = start_idx + clip_size - 1
+ timebase = video.duration / num_frames
+ video_start_pts = int(start_idx * timebase)
+ video_end_pts = int(end_idx * timebase)
+ seek_offset = max(video_start_pts - 1024, 0)
+ container.seek(seek_offset, any_frame=False, backward=True, stream=video)
+ frames = {}
+ for frame in container.decode(video=0):
+ if frame.pts < video_start_pts:
+ continue
+ frames[frame.pts] = frame
+ if frame.pts > video_end_pts:
+ break
+ frames = [frames[pts] for pts in sorted(frames)]
+ return frames, fps
+
+
+def decode(container, sampling_rate, num_frames, clip_idx, num_clips, target_fps):
+ '''
+ Decode the video and perform temporal sampling.
+ Args:
+ container (container): pyav container.
+ sampling_rate (int): frame sampling rate (interval between two sampled frames).
+ num_frames (int): number of frames to sample.
+ clip_idx (int): if clip_idx is -1, perform random temporal sampling.
+ If clip_idx is larger than -1, uniformly split the video to num_clips
+ clips, and select the clip_idx-th video clip.
+ num_clips (int): overall number of clips to uniformly sample from the given video.
+ target_fps (int): the input video may have different fps, convert it to
+ the target video fps before frame sampling.
+ Returns:
+ frames (tensor): decoded frames from the video.
+ '''
+ assert clip_idx >= -2, "Not a valied clip_idx {}".format(clip_idx)
+ frames, fps = pyav_decode(container, sampling_rate, num_frames, clip_idx, num_clips, target_fps)
+ clip_size = sampling_rate * num_frames / target_fps * fps
+ index = np.linspace(0, clip_size - 1, num_frames)
+ index = np.clip(index, 0, len(frames) - 1).astype(np.int64)
+ frames = np.array([frames[idx].to_rgb().to_ndarray() for idx in index])
+ frames = frames.transpose(0, 3, 1, 2)
+ return frames
+
+
+file = hf_hub_download(repo_id="Intel/tvp_demo", filename="AK2KG.mp4", repo_type="dataset")
+model = TvpForVideoGrounding.from_pretrained("Intel/tvp-base")
+
+decoder_kwargs = dict(
+ container=av.open(file, metadata_errors="ignore"),
+ sampling_rate=1,
+ num_frames=model.config.num_frames,
+ clip_idx=0,
+ num_clips=1,
+ target_fps=3,
+)
+raw_sampled_frms = decode(**decoder_kwargs)
+
+text = "a person is sitting on a bed."
+processor = AutoProcessor.from_pretrained("Intel/tvp-base")
+model_inputs = processor(
+ text=[text], videos=list(raw_sampled_frms), return_tensors="pt", max_text_length=100#, size=size
+)
+
+model_inputs["pixel_values"] = model_inputs["pixel_values"].to(model.dtype)
+output = model(**model_inputs)
+
+def get_video_duration(filename):
+ cap = cv2.VideoCapture(filename)
+ if cap.isOpened():
+ rate = cap.get(5)
+ frame_num = cap.get(7)
+ duration = frame_num/rate
+ return duration
+ return -1
+
+duration = get_video_duration(file)
+start, end = processor.post_process_video_grounding(output.logits, duration)
+
+print(f"The time slot of the video corresponding to the text \"{text}\" is from {start}s to {end}s")
+```
+
+Tips:
+
+- This implementation of TVP uses [`BertTokenizer`] to generate text embeddings and Resnet-50 model to compute visual embeddings.
+- Checkpoints for pre-trained [tvp-base](https://huggingface.co/Intel/tvp-base) is released.
+- Please refer to [Table 2](https://arxiv.org/pdf/2303.04995.pdf) for TVP's performance on Temporal Video Grounding task.
+
+
+## TvpConfig
+
+[[autodoc]] TvpConfig
+
+## TvpImageProcessor
+
+[[autodoc]] TvpImageProcessor
+ - preprocess
+
+## TvpProcessor
+
+[[autodoc]] TvpProcessor
+ - __call__
+
+## TvpModel
+
+[[autodoc]] TvpModel
+ - forward
+
+## TvpForVideoGrounding
+
+[[autodoc]] TvpForVideoGrounding
+ - forward
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/udop.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/udop.md
new file mode 100644
index 0000000000000000000000000000000000000000..614bd2ff4fd7156e094b83f20dfb4a76bf32a4cf
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/udop.md
@@ -0,0 +1,113 @@
+
+
+# UDOP
+
+## Overview
+
+The UDOP model was proposed in [Unifying Vision, Text, and Layout for Universal Document Processing](https://arxiv.org/abs/2212.02623) by Zineng Tang, Ziyi Yang, Guoxin Wang, Yuwei Fang, Yang Liu, Chenguang Zhu, Michael Zeng, Cha Zhang, Mohit Bansal.
+UDOP adopts an encoder-decoder Transformer architecture based on [T5](t5) for document AI tasks like document image classification, document parsing and document visual question answering.
+
+The abstract from the paper is the following:
+
+We propose Universal Document Processing (UDOP), a foundation Document AI model which unifies text, image, and layout modalities together with varied task formats, including document understanding and generation. UDOP leverages the spatial correlation between textual content and document image to model image, text, and layout modalities with one uniform representation. With a novel Vision-Text-Layout Transformer, UDOP unifies pretraining and multi-domain downstream tasks into a prompt-based sequence generation scheme. UDOP is pretrained on both large-scale unlabeled document corpora using innovative self-supervised objectives and diverse labeled data. UDOP also learns to generate document images from text and layout modalities via masked image reconstruction. To the best of our knowledge, this is the first time in the field of document AI that one model simultaneously achieves high-quality neural document editing and content customization. Our method sets the state-of-the-art on 9 Document AI tasks, e.g., document understanding and QA, across diverse data domains like finance reports, academic papers, and websites. UDOP ranks first on the leaderboard of the Document Understanding Benchmark (DUE).*
+
+
 +
+ UDOP architecture. Taken from the original paper.
+
+## Usage tips
+
+- In addition to *input_ids*, [`UdopForConditionalGeneration`] also expects the input `bbox`, which are
+ the bounding boxes (i.e. 2D-positions) of the input tokens. These can be obtained using an external OCR engine such
+ as Google's [Tesseract](https://github.com/tesseract-ocr/tesseract) (there's a [Python wrapper](https://pypi.org/project/pytesseract/) available). Each bounding box should be in (x0, y0, x1, y1) format, where (x0, y0) corresponds to the position of the upper left corner in the bounding box, and (x1, y1) represents the
+ position of the lower right corner. Note that one first needs to normalize the bounding boxes to be on a 0-1000
+ scale. To normalize, you can use the following function:
+
+```python
+def normalize_bbox(bbox, width, height):
+ return [
+ int(1000 * (bbox[0] / width)),
+ int(1000 * (bbox[1] / height)),
+ int(1000 * (bbox[2] / width)),
+ int(1000 * (bbox[3] / height)),
+ ]
+```
+
+Here, `width` and `height` correspond to the width and height of the original document in which the token
+occurs. Those can be obtained using the Python Image Library (PIL) library for example, as follows:
+
+```python
+from PIL import Image
+
+# Document can be a png, jpg, etc. PDFs must be converted to images.
+image = Image.open(name_of_your_document).convert("RGB")
+
+width, height = image.size
+```
+
+One can use [`UdopProcessor`] to prepare images and text for the model, which takes care of all of this. By default, this class uses the Tesseract engine to extract a list of words and boxes (coordinates) from a given document. Its functionality is equivalent to that of [`LayoutLMv3Processor`], hence it supports passing either `apply_ocr=False` in case you prefer to use your own OCR engine or `apply_ocr=True` in case you want the default OCR engine to be used. Refer to the [usage guide of LayoutLMv2](layoutlmv2#usage-layoutlmv2processor) regarding all possible use cases (the functionality of `UdopProcessor` is identical).
+
+- If using an own OCR engine of choice, one recommendation is Azure's [Read API](https://learn.microsoft.com/en-us/azure/ai-services/computer-vision/how-to/call-read-api), which supports so-called line segments. Use of segment position embeddings typically results in better performance.
+- At inference time, it's recommended to use the `generate` method to autoregressively generate text given a document image.
+- The model has been pre-trained on both self-supervised and supervised objectives. One can use the various task prefixes (prompts) used during pre-training to test out the out-of-the-box capabilities. For instance, the model can be prompted with "Question answering. What is the date?", as "Question answering." is the task prefix used during pre-training for DocVQA. Refer to the [paper](https://arxiv.org/abs/2212.02623) (table 1) for all task prefixes.
+- One can also fine-tune [`UdopEncoderModel`], which is the encoder-only part of UDOP, which can be seen as a LayoutLMv3-like Transformer encoder. For discriminative tasks, one can just add a linear classifier on top of it and fine-tune it on a labeled dataset.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/microsoft/UDOP).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with UDOP. If
+you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll
+review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- Demo notebooks regarding UDOP can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/UDOP) that show how
+to fine-tune UDOP on a custom dataset as well as inference. 🌎
+- [Document question answering task guide](../tasks/document_question_answering)
+
+## UdopConfig
+
+[[autodoc]] UdopConfig
+
+## UdopTokenizer
+
+[[autodoc]] UdopTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## UdopTokenizerFast
+
+[[autodoc]] UdopTokenizerFast
+
+## UdopProcessor
+
+[[autodoc]] UdopProcessor
+ - __call__
+
+## UdopModel
+
+[[autodoc]] UdopModel
+ - forward
+
+## UdopForConditionalGeneration
+
+[[autodoc]] UdopForConditionalGeneration
+ - forward
+
+## UdopEncoderModel
+
+[[autodoc]] UdopEncoderModel
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/ul2.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/ul2.md
new file mode 100644
index 0000000000000000000000000000000000000000..f4d01c40b0c10944e5ddb3451f355e4c95bf2d9a
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/ul2.md
@@ -0,0 +1,43 @@
+
+
+# UL2
+
+## Overview
+
+The T5 model was presented in [Unifying Language Learning Paradigms](https://arxiv.org/pdf/2205.05131v1.pdf) by Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler.
+
+The abstract from the paper is the following:
+
+*Existing pre-trained models are generally geared towards a particular class of problems. To date, there seems to be still no consensus on what the right architecture and pre-training setup should be. This paper presents a unified framework for pre-training models that are universally effective across datasets and setups. We begin by disentangling architectural archetypes with pre-training objectives -- two concepts that are commonly conflated. Next, we present a generalized and unified perspective for self-supervision in NLP and show how different pre-training objectives can be cast as one another and how interpolating between different objectives can be effective. We then propose Mixture-of-Denoisers (MoD), a pre-training objective that combines diverse pre-training paradigms together. We furthermore introduce a notion of mode switching, wherein downstream fine-tuning is associated with specific pre-training schemes. We conduct extensive ablative experiments to compare multiple pre-training objectives and find that our method pushes the Pareto-frontier by outperforming T5 and/or GPT-like models across multiple diverse setups. Finally, by scaling our model up to 20B parameters, we achieve SOTA performance on 50 well-established supervised NLP tasks ranging from language generation (with automated and human evaluation), language understanding, text classification, question answering, commonsense reasoning, long text reasoning, structured knowledge grounding and information retrieval. Our model also achieve strong results at in-context learning, outperforming 175B GPT-3 on zero-shot SuperGLUE and tripling the performance of T5-XXL on one-shot summarization.*
+
+This model was contributed by [DanielHesslow](https://huggingface.co/Seledorn). The original code can be found [here](https://github.com/google-research/google-research/tree/master/ul2).
+
+## Usage tips
+
+- UL2 is an encoder-decoder model pre-trained on a mixture of denoising functions as well as fine-tuned on an array of downstream tasks.
+- UL2 has the same architecture as [T5v1.1](t5v1.1) but uses the Gated-SiLU activation function instead of Gated-GELU.
+- The authors release checkpoints of one architecture which can be seen [here](https://huggingface.co/google/ul2)
+
+
 +
+ UPerNet framework. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code is based on OpenMMLab's mmsegmentation [here](https://github.com/open-mmlab/mmsegmentation/blob/master/mmseg/models/decode_heads/uper_head.py).
+
+## Usage examples
+
+UPerNet is a general framework for semantic segmentation. It can be used with any vision backbone, like so:
+
+```py
+from transformers import SwinConfig, UperNetConfig, UperNetForSemanticSegmentation
+
+backbone_config = SwinConfig(out_features=["stage1", "stage2", "stage3", "stage4"])
+
+config = UperNetConfig(backbone_config=backbone_config)
+model = UperNetForSemanticSegmentation(config)
+```
+
+To use another vision backbone, like [ConvNeXt](convnext), simply instantiate the model with the appropriate backbone:
+
+```py
+from transformers import ConvNextConfig, UperNetConfig, UperNetForSemanticSegmentation
+
+backbone_config = ConvNextConfig(out_features=["stage1", "stage2", "stage3", "stage4"])
+
+config = UperNetConfig(backbone_config=backbone_config)
+model = UperNetForSemanticSegmentation(config)
+```
+
+Note that this will randomly initialize all the weights of the model.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with UPerNet.
+
+- Demo notebooks for UPerNet can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/UPerNet).
+- [`UperNetForSemanticSegmentation`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/semantic-segmentation) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/semantic_segmentation.ipynb).
+- See also: [Semantic segmentation task guide](../tasks/semantic_segmentation)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## UperNetConfig
+
+[[autodoc]] UperNetConfig
+
+## UperNetForSemanticSegmentation
+
+[[autodoc]] UperNetForSemanticSegmentation
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/van.md b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/van.md
new file mode 100644
index 0000000000000000000000000000000000000000..2fb8475ce72f3285904df831617a8450d3300776
--- /dev/null
+++ b/tasks/tasksmith-5dd11b34cce1/tests/source/docs/source/en/model_doc/van.md
@@ -0,0 +1,72 @@
+
+
+# VAN
+
+
 +
+This model was contributed by [Francesco](https://huggingface.co/Francesco). The original code can be found [here](https://github.com/Visual-Attention-Network/VAN-Classification).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with VAN.
+
+
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +