diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/inference.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/inference.py
new file mode 100644
index 0000000000000000000000000000000000000000..35c99399baba62f77bbaac8adf4e2eacdbabf779
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/inference.py
@@ -0,0 +1,186 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import math
+from types import MethodType
+from typing import Any, Optional, Union
+
+from .state import PartialState
+from .utils import (
+ calculate_maximum_sizes,
+ convert_bytes,
+ copy_tensor_to_devices,
+ ignorant_find_batch_size,
+ infer_auto_device_map,
+ is_pippy_available,
+ pad_input_tensors,
+ send_to_device,
+)
+
+
+def generate_device_map(
+ model, num_processes: int = 1, no_split_module_classes=None, max_memory: Optional[dict] = None
+):
+ """
+ Calculates the device map for `model` with an offset for PiPPy
+ """
+ if num_processes == 1:
+ return infer_auto_device_map(model, no_split_module_classes=no_split_module_classes, clean_result=False)
+ if max_memory is None:
+ model_size, shared = calculate_maximum_sizes(model)
+
+ # Split into `n` chunks for each GPU
+ memory = (model_size + shared[0]) / num_processes
+ memory = convert_bytes(memory)
+ value, ending = memory.split(" ")
+
+ # Add a chunk to deal with potential extra shared memory instances
+ memory = math.ceil(float(value)) * 1.1
+ memory = f"{memory} {ending}"
+ max_memory = {i: memory for i in range(num_processes)}
+ device_map = infer_auto_device_map(
+ model,
+ max_memory=max_memory,
+ no_split_module_classes=no_split_module_classes,
+ clean_result=False,
+ )
+ return device_map
+
+
+def find_pippy_batch_size(args, kwargs):
+ found_batch_size = None
+ if args is not None:
+ for arg in args:
+ found_batch_size = ignorant_find_batch_size(arg)
+ if found_batch_size is not None:
+ break
+ if kwargs is not None and found_batch_size is None:
+ for kwarg in kwargs.values():
+ found_batch_size = ignorant_find_batch_size(kwarg)
+ if found_batch_size is not None:
+ break
+ return found_batch_size
+
+
+def build_pipeline(model, split_points, args, kwargs, num_chunks):
+ """
+ Attaches the split points to the model based on `self.device_map` and generates a `PipelineStage`. Requires passing
+ in needed `args` and `kwargs` as the model needs on the CPU.
+
+ Users can pass in custom `num_chunks` as an optional hyper-parameter. By default will use
+ `AcceleratorState.num_processes`
+ """
+ # Note: We import here to reduce import time from general modules, and isolate outside dependencies
+ from torch.distributed.pipelining import ScheduleGPipe, SplitPoint, pipeline
+
+ # We need to annotate the split points in the model for PiPPy
+ state = PartialState()
+ split_spec = {split_point: SplitPoint.BEGINNING for split_point in split_points}
+ pipe = pipeline(
+ model,
+ mb_args=args,
+ mb_kwargs=kwargs,
+ split_spec=split_spec,
+ )
+ stage = pipe.build_stage(state.local_process_index, device=state.device)
+ schedule = ScheduleGPipe(stage, num_chunks)
+
+ return schedule
+
+
+def pippy_forward(forward, num_chunks, gather_output, *args, **kwargs):
+ state = PartialState()
+ output = None
+
+ if state.num_processes == 1:
+ output = forward(*args, **kwargs)
+ elif state.is_local_main_process:
+ found_batch_size = find_pippy_batch_size(args, kwargs)
+ if found_batch_size is None:
+ raise ValueError("Could not find batch size from args or kwargs")
+ else:
+ if found_batch_size != num_chunks:
+ args = pad_input_tensors(args, found_batch_size, num_chunks)
+ kwargs = pad_input_tensors(kwargs, found_batch_size, num_chunks)
+ forward(*args, **kwargs)
+ elif state.is_last_process:
+ output = forward()
+ else:
+ forward()
+ if gather_output:
+ # Each node will get a copy of the full output which is only on the last GPU
+ output = copy_tensor_to_devices(output)
+ return output
+
+
+def prepare_pippy(
+ model,
+ split_points: Optional[Union[str, list[str]]] = "auto",
+ no_split_module_classes: Optional[list[str]] = None,
+ example_args: Optional[tuple[Any]] = (),
+ example_kwargs: Optional[dict[str, Any]] = None,
+ num_chunks: Optional[int] = None,
+ gather_output: Optional[bool] = False,
+):
+ """
+ Wraps `model` for pipeline parallel inference.
+
+ Args:
+ model (`torch.nn.Module`):
+ A model we want to split for pipeline-parallel inference
+ split_points (`str` or `List[str]`, defaults to 'auto'):
+ How to generate the split points and chunk the model across each GPU. 'auto' will find the best balanced
+ split given any model. Should be a list of layer names in the model to split by otherwise.
+ no_split_module_classes (`List[str]`):
+ A list of class names for layers we don't want to be split.
+ example_args (tuple of model inputs):
+ The expected inputs for the model that uses order-based inputs for a *single process*. Recommended to use
+ this method if possible.
+ example_kwargs (dict of model inputs)
+ The expected inputs for the model that uses dictionary-based inputs for a *single process*. This is a
+ *highly* limiting structure that requires the same keys be present at *all* inference calls. Not
+ recommended unless the prior condition is true for all cases.
+ num_chunks (`int`, defaults to the number of available GPUs):
+ The number of different stages the Pipeline will have. By default it will assign one chunk per GPU, but
+ this can be tuned and played with. In general one should have num_chunks >= num_gpus.
+ gather_output (`bool`, defaults to `False`):
+ If `True`, the output from the last GPU (which holds the true outputs) is sent across to all GPUs.
+ """
+ if not is_pippy_available():
+ raise ImportError("Using `torch.distributed.pipelining` requires PyTorch 2.4.0 or later.")
+ state = PartialState()
+ example_args = send_to_device(example_args, "cpu")
+ example_kwargs = send_to_device(example_kwargs, "cpu")
+ if num_chunks is None:
+ num_chunks = state.num_processes
+ if split_points == "auto":
+ device_map = generate_device_map(model, num_chunks, no_split_module_classes=no_split_module_classes)
+ split_points = []
+ for i in range(1, num_chunks):
+ split_points.append(next(k for k, v in device_map.items() if v == i))
+ model.hf_split_points = split_points
+ stage = build_pipeline(model, split_points, example_args, example_kwargs, num_chunks)
+ model._original_forward = model.forward
+ model._original_call = model.__call__
+ model.pippy_stage = stage
+ model.hf_split_points = split_points
+
+ def forward(*args, **kwargs):
+ return pippy_forward(stage.step, num_chunks, gather_output, *args, **kwargs)
+
+ # To act like a decorator so that it can be popped when doing `extract_model_from_parallel`
+ # Note: creates an infinite recursion loop with `generate`
+ model_forward = MethodType(forward, model)
+ forward.__wrapped__ = model_forward
+ model.forward = forward
+ return model
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/launchers.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/launchers.py
new file mode 100644
index 0000000000000000000000000000000000000000..d811c1622e8f3fc4d7535902af54274a49b5b03d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/launchers.py
@@ -0,0 +1,307 @@
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import os
+import sys
+import tempfile
+
+import torch
+
+from .state import AcceleratorState, PartialState
+from .utils import (
+ PrecisionType,
+ PrepareForLaunch,
+ are_libraries_initialized,
+ check_cuda_p2p_ib_support,
+ get_current_device_type,
+ get_gpu_info,
+ is_mps_available,
+ is_torch_version,
+ patch_environment,
+)
+from .utils.constants import ELASTIC_LOG_LINE_PREFIX_TEMPLATE_PYTORCH_VERSION
+
+
+def test_launch():
+ "Verify a `PartialState` can be initialized."
+ _ = PartialState()
+
+
+def notebook_launcher(
+ function,
+ args=(),
+ num_processes=None,
+ mixed_precision="no",
+ use_port="29500",
+ master_addr="127.0.0.1",
+ node_rank=0,
+ num_nodes=1,
+ rdzv_backend="static",
+ rdzv_endpoint="",
+ rdzv_conf=None,
+ rdzv_id="none",
+ max_restarts=0,
+ monitor_interval=0.1,
+ log_line_prefix_template=None,
+):
+ """
+ Launches a training function, using several processes or multiple nodes if it's possible in the current environment
+ (TPU with multiple cores for instance).
+
+
+
+ To use this function absolutely zero calls to a device must be made in the notebook session before calling. If any
+ have been made, you will need to restart the notebook and make sure no cells use any device capability.
+
+ Setting `ACCELERATE_DEBUG_MODE="1"` in your environment will run a test before truly launching to ensure that none
+ of those calls have been made.
+
+
+
+ Args:
+ function (`Callable`):
+ The training function to execute. If it accepts arguments, the first argument should be the index of the
+ process run.
+ args (`Tuple`):
+ Tuple of arguments to pass to the function (it will receive `*args`).
+ num_processes (`int`, *optional*):
+ The number of processes to use for training. Will default to 8 in Colab/Kaggle if a TPU is available, to
+ the number of devices available otherwise.
+ mixed_precision (`str`, *optional*, defaults to `"no"`):
+ If `fp16` or `bf16`, will use mixed precision training on multi-device.
+ use_port (`str`, *optional*, defaults to `"29500"`):
+ The port to use to communicate between processes when launching a multi-device training.
+ master_addr (`str`, *optional*, defaults to `"127.0.0.1"`):
+ The address to use for communication between processes.
+ node_rank (`int`, *optional*, defaults to 0):
+ The rank of the current node.
+ num_nodes (`int`, *optional*, defaults to 1):
+ The number of nodes to use for training.
+ rdzv_backend (`str`, *optional*, defaults to `"static"`):
+ The rendezvous method to use, such as 'static' (the default) or 'c10d'
+ rdzv_endpoint (`str`, *optional*, defaults to `""`):
+ The endpoint of the rdzv sync. storage.
+ rdzv_conf (`Dict`, *optional*, defaults to `None`):
+ Additional rendezvous configuration.
+ rdzv_id (`str`, *optional*, defaults to `"none"`):
+ The unique run id of the job.
+ max_restarts (`int`, *optional*, defaults to 0):
+ The maximum amount of restarts that elastic agent will conduct on workers before failure.
+ monitor_interval (`float`, *optional*, defaults to 0.1):
+ The interval in seconds that is used by the elastic_agent as a period of monitoring workers.
+ log_line_prefix_template (`str`, *optional*, defaults to `None`):
+ The prefix template for elastic launch logging. Available from PyTorch 2.2.0.
+
+ Example:
+
+ ```python
+ # Assume this is defined in a Jupyter Notebook on an instance with two devices
+ from accelerate import notebook_launcher
+
+
+ def train(*args):
+ # Your training function here
+ ...
+
+
+ notebook_launcher(train, args=(arg1, arg2), num_processes=2, mixed_precision="fp16")
+ ```
+ """
+ # Are we in a google colab or a Kaggle Kernel?
+ in_colab = False
+ in_kaggle = False
+ if any(key.startswith("KAGGLE") for key in os.environ.keys()):
+ in_kaggle = True
+ elif "IPython" in sys.modules:
+ in_colab = "google.colab" in str(sys.modules["IPython"].get_ipython())
+
+ try:
+ mixed_precision = PrecisionType(mixed_precision.lower())
+ except ValueError:
+ raise ValueError(
+ f"Unknown mixed_precision mode: {args.mixed_precision.lower()}. Choose between {PrecisionType.list()}."
+ )
+
+ if (in_colab or in_kaggle) and (
+ (os.environ.get("TPU_NAME", None) is not None) or (os.environ.get("PJRT_DEVICE", "") == "TPU")
+ ):
+ # TPU launch
+ import torch_xla.distributed.xla_multiprocessing as xmp
+
+ if len(AcceleratorState._shared_state) > 0:
+ raise ValueError(
+ "To train on TPU in Colab or Kaggle Kernel, the `Accelerator` should only be initialized inside "
+ "your training function. Restart your notebook and make sure no cells initializes an "
+ "`Accelerator`."
+ )
+
+ launcher = PrepareForLaunch(function, distributed_type="XLA")
+ print("Launching a training on TPU cores.")
+ xmp.spawn(launcher, args=args, start_method="fork")
+ elif in_colab and get_gpu_info()[1] < 2:
+ # No need for a distributed launch otherwise as it's either CPU or one GPU.
+ if torch.cuda.is_available():
+ print("Launching training on one GPU.")
+ else:
+ print("Launching training on one CPU.")
+ function(*args)
+ else:
+ if num_processes is None:
+ raise ValueError(
+ "You have to specify the number of devices you would like to use, add `num_processes=...` to your call."
+ )
+ if node_rank >= num_nodes:
+ raise ValueError("The node_rank must be less than the number of nodes.")
+ if num_processes > 1:
+ # Multi-device launch
+ from torch.distributed.launcher.api import LaunchConfig, elastic_launch
+ from torch.multiprocessing import start_processes
+ from torch.multiprocessing.spawn import ProcessRaisedException
+
+ if len(AcceleratorState._shared_state) > 0:
+ raise ValueError(
+ "To launch a multi-device training from your notebook, the `Accelerator` should only be initialized "
+ "inside your training function. Restart your notebook and make sure no cells initializes an "
+ "`Accelerator`."
+ )
+ # Check for specific libraries known to initialize device that users constantly use
+ problematic_imports = are_libraries_initialized("bitsandbytes")
+ if len(problematic_imports) > 0:
+ err = (
+ "Could not start distributed process. Libraries known to initialize device upon import have been "
+ "imported already. Please keep these imports inside your training function to try and help with this:"
+ )
+ for lib_name in problematic_imports:
+ err += f"\n\t* `{lib_name}`"
+ raise RuntimeError(err)
+
+ patched_env = dict(
+ nproc=num_processes,
+ node_rank=node_rank,
+ world_size=num_nodes * num_processes,
+ master_addr=master_addr,
+ master_port=use_port,
+ mixed_precision=mixed_precision,
+ )
+
+ # Check for CUDA P2P and IB issues
+ if not check_cuda_p2p_ib_support():
+ patched_env["nccl_p2p_disable"] = "1"
+ patched_env["nccl_ib_disable"] = "1"
+
+ # torch.distributed will expect a few environment variable to be here. We set the ones common to each
+ # process here (the other ones will be set be the launcher).
+ with patch_environment(**patched_env):
+ # First dummy launch
+ # Determine device type without initializing any device (which would break fork)
+ device_type, distributed_type = get_current_device_type()
+ if os.environ.get("ACCELERATE_DEBUG_MODE", "false").lower() == "true":
+ launcher = PrepareForLaunch(test_launch, distributed_type=distributed_type)
+ try:
+ start_processes(launcher, args=(), nprocs=num_processes, start_method="fork")
+ except ProcessRaisedException as e:
+ err = "An issue was found when verifying a stable environment for the notebook launcher."
+ if f"Cannot re-initialize {device_type.upper()} in forked subprocess" in e.args[0]:
+ raise RuntimeError(
+ f"{err}"
+ "This likely stems from an outside import causing issues once the `notebook_launcher()` is called. "
+ "Please review your imports and test them when running the `notebook_launcher()` to identify "
+ f"which one is problematic and causing {device_type.upper()} to be initialized."
+ ) from e
+ else:
+ raise RuntimeError(f"{err} The following error was raised: {e}") from e
+ # Now the actual launch
+ launcher = PrepareForLaunch(function, distributed_type=distributed_type)
+ print(f"Launching training on {num_processes} {device_type.upper()}s.")
+ try:
+ if rdzv_conf is None:
+ rdzv_conf = {}
+ if rdzv_backend == "static":
+ rdzv_conf["rank"] = node_rank
+ if not rdzv_endpoint:
+ rdzv_endpoint = f"{master_addr}:{use_port}"
+ launch_config_kwargs = dict(
+ min_nodes=num_nodes,
+ max_nodes=num_nodes,
+ nproc_per_node=num_processes,
+ run_id=rdzv_id,
+ rdzv_endpoint=rdzv_endpoint,
+ rdzv_backend=rdzv_backend,
+ rdzv_configs=rdzv_conf,
+ max_restarts=max_restarts,
+ monitor_interval=monitor_interval,
+ start_method="fork",
+ )
+ if is_torch_version(">=", ELASTIC_LOG_LINE_PREFIX_TEMPLATE_PYTORCH_VERSION):
+ launch_config_kwargs["log_line_prefix_template"] = log_line_prefix_template
+ elastic_launch(config=LaunchConfig(**launch_config_kwargs), entrypoint=function)(*args)
+ except ProcessRaisedException as e:
+ if f"Cannot re-initialize {device_type.upper()} in forked subprocess" in e.args[0]:
+ raise RuntimeError(
+ f"{device_type.upper()} has been initialized before the `notebook_launcher` could create a forked subprocess. "
+ "This likely stems from an outside import causing issues once the `notebook_launcher()` is called. "
+ "Please review your imports and test them when running the `notebook_launcher()` to identify "
+ f"which one is problematic and causing {device_type.upper()} to be initialized."
+ ) from e
+ else:
+ raise RuntimeError(f"An issue was found when launching the training: {e}") from e
+
+ else:
+ # No need for a distributed launch otherwise as it's either CPU, GPU, XPU or MPS.
+ if is_mps_available():
+ os.environ["PYTORCH_ENABLE_MPS_FALLBACK"] = "1"
+ print("Launching training on MPS.")
+ elif torch.cuda.is_available():
+ print("Launching training on one GPU.")
+ elif torch.xpu.is_available():
+ print("Launching training on one XPU.")
+ else:
+ print("Launching training on CPU.")
+ function(*args)
+
+
+def debug_launcher(function, args=(), num_processes=2):
+ """
+ Launches a training function using several processes on CPU for debugging purposes.
+
+
+
+ This function is provided for internal testing and debugging, but it's not intended for real trainings. It will
+ only use the CPU.
+
+
+
+ Args:
+ function (`Callable`):
+ The training function to execute.
+ args (`Tuple`):
+ Tuple of arguments to pass to the function (it will receive `*args`).
+ num_processes (`int`, *optional*, defaults to 2):
+ The number of processes to use for training.
+ """
+ from torch.multiprocessing import start_processes
+
+ with tempfile.NamedTemporaryFile() as tmp_file:
+ # torch.distributed will expect a few environment variable to be here. We set the ones common to each
+ # process here (the other ones will be set be the launcher).
+ with patch_environment(
+ world_size=num_processes,
+ master_addr="127.0.0.1",
+ master_port="29500",
+ accelerate_mixed_precision="no",
+ accelerate_debug_rdv_file=tmp_file.name,
+ accelerate_use_cpu="yes",
+ ):
+ launcher = PrepareForLaunch(function, debug=True)
+ start_processes(launcher, args=args, nprocs=num_processes, start_method="fork")
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/local_sgd.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/local_sgd.py
new file mode 100644
index 0000000000000000000000000000000000000000..5913d2d03df3c67ccf3e9ef84e75e06dc694b1fa
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/local_sgd.py
@@ -0,0 +1,106 @@
+# Copyright 2023 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import torch
+
+from accelerate import Accelerator, DistributedType
+
+
+class LocalSGD:
+ """
+ A helper class to support local SGD on top of Accelerator. It simply runs a given number of updates independently
+ on each device, and averages model weights every K synchronization step.
+
+ It should be used only in the multi-GPU (or multi-CPU) setup without extensions such as DeepSpeed. In particular,
+ this is a simple implementation that cannot support scenarios such as model parallelism.
+
+
+ Although we are not aware of the true origins of this simple approach, the idea of local SGD is quite old and goes
+ back to at least:
+
+ Zhang, J., De Sa, C., Mitliagkas, I., & Ré, C. (2016). [Parallel SGD: When does averaging help?. arXiv preprint
+ arXiv:1606.07365.](https://huggingface.co/papers/1606.07365)
+
+ We credit the term Local SGD to the following paper (but there might be earlier references we are not aware of).
+
+ Stich, Sebastian Urban. ["Local SGD Converges Fast and Communicates Little." ICLR 2019-International Conference on
+ Learning Representations. No. CONF. 2019.](https://huggingface.co/papers/1805.09767)
+
+ """
+
+ def __enter__(self):
+ if self.enabled:
+ self.model_sync_obj = self.model.no_sync()
+ self.model_sync_obj.__enter__()
+
+ return self
+
+ def __exit__(self, type, value, tb):
+ if self.enabled:
+ # Average all models on exit
+ self._sync_and_avg_model_params()
+ self.model_sync_obj.__exit__(type, value, tb)
+
+ def __init__(self, accelerator: Accelerator, model: torch.nn.Module, local_sgd_steps: int, enabled: bool = True):
+ """
+ Constructor.
+
+ Args:
+ model (`torch.nn.Module):
+ The model whose parameters we need to average.
+ accelerator (`Accelerator`):
+ Accelerator object.
+ local_sgd_steps (`int`):
+ A number of local SGD steps (before model parameters are synchronized).
+ enabled (`bool):
+ Local SGD is disabled if this parameter set to `False`.
+ """
+ if accelerator.distributed_type not in [
+ DistributedType.NO,
+ DistributedType.MULTI_CPU,
+ DistributedType.MULTI_GPU,
+ DistributedType.MULTI_XPU,
+ DistributedType.MULTI_MLU,
+ DistributedType.MULTI_HPU,
+ DistributedType.MULTI_SDAA,
+ DistributedType.MULTI_MUSA,
+ DistributedType.MULTI_NPU,
+ ]:
+ raise NotImplementedError("LocalSGD is supported only for CPUs and GPUs (no DeepSpeed or MegatronLM)")
+ self.enabled = enabled and accelerator.distributed_type != DistributedType.NO
+ self.num_steps = 0
+ if self.enabled:
+ self.accelerator = accelerator
+ self.model = model
+ self.local_sgd_steps = local_sgd_steps
+
+ def step(self):
+ """
+ This function makes a "step" and synchronizes model parameters if necessary.
+ """
+ self.num_steps += 1
+ if not self.enabled:
+ return
+
+ if self.num_steps % self.local_sgd_steps == 0:
+ self._sync_and_avg_model_params()
+
+ def _sync_and_avg_model_params(self):
+ """
+ Synchronize + Average model parameters across all GPUs
+ """
+
+ self.accelerator.wait_for_everyone()
+ with self.accelerator.autocast():
+ for param in self.model.parameters():
+ param.data = self.accelerator.reduce(param.data, reduction="mean")
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/logging.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/logging.py
new file mode 100644
index 0000000000000000000000000000000000000000..172445c305b2d469c26997df35a97c1c22fe25ed
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/logging.py
@@ -0,0 +1,126 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import functools
+import logging
+import os
+from typing import Optional
+
+from .state import PartialState
+
+
+class MultiProcessAdapter(logging.LoggerAdapter):
+ """
+ An adapter to assist with logging in multiprocess.
+
+ `log` takes in an additional `main_process_only` kwarg, which dictates whether it should be called on all processes
+ or only the main executed one. Default is `main_process_only=True`.
+
+ Does not require an `Accelerator` object to be created first.
+ """
+
+ @staticmethod
+ def _should_log(main_process_only):
+ "Check if log should be performed"
+ state = PartialState()
+ return not main_process_only or (main_process_only and state.is_main_process)
+
+ def log(self, level, msg, *args, **kwargs):
+ """
+ Delegates logger call after checking if we should log.
+
+ Accepts a new kwarg of `main_process_only`, which will dictate whether it will be logged across all processes
+ or only the main executed one. Default is `True` if not passed
+
+ Also accepts "in_order", which if `True` makes the processes log one by one, in order. This is much easier to
+ read, but comes at the cost of sometimes needing to wait for the other processes. Default is `False` to not
+ break with the previous behavior.
+
+ `in_order` is ignored if `main_process_only` is passed.
+ """
+ if PartialState._shared_state == {}:
+ raise RuntimeError(
+ "You must initialize the accelerate state by calling either `PartialState()` or `Accelerator()` before using the logging utility."
+ )
+ main_process_only = kwargs.pop("main_process_only", True)
+ in_order = kwargs.pop("in_order", False)
+ # set `stacklevel` to exclude ourself in `Logger.findCaller()` while respecting user's choice
+ kwargs.setdefault("stacklevel", 2)
+
+ if self.isEnabledFor(level):
+ if self._should_log(main_process_only):
+ msg, kwargs = self.process(msg, kwargs)
+ self.logger.log(level, msg, *args, **kwargs)
+
+ elif in_order:
+ state = PartialState()
+ for i in range(state.num_processes):
+ if i == state.process_index:
+ msg, kwargs = self.process(msg, kwargs)
+ self.logger.log(level, msg, *args, **kwargs)
+ state.wait_for_everyone()
+
+ @functools.lru_cache(None)
+ def warning_once(self, *args, **kwargs):
+ """
+ This method is identical to `logger.warning()`, but will emit the warning with the same message only once
+
+ Note: The cache is for the function arguments, so 2 different callers using the same arguments will hit the
+ cache. The assumption here is that all warning messages are unique across the code. If they aren't then need to
+ switch to another type of cache that includes the caller frame information in the hashing function.
+ """
+ self.warning(*args, **kwargs)
+
+
+def get_logger(name: str, log_level: Optional[str] = None):
+ """
+ Returns a `logging.Logger` for `name` that can handle multiprocessing.
+
+ If a log should be called on all processes, pass `main_process_only=False` If a log should be called on all
+ processes and in order, also pass `in_order=True`
+
+ Args:
+ name (`str`):
+ The name for the logger, such as `__file__`
+ log_level (`str`, *optional*):
+ The log level to use. If not passed, will default to the `LOG_LEVEL` environment variable, or `INFO` if not
+
+ Example:
+
+ ```python
+ >>> from accelerate.logging import get_logger
+ >>> from accelerate import Accelerator
+
+ >>> logger = get_logger(__name__)
+
+ >>> accelerator = Accelerator()
+ >>> logger.info("My log", main_process_only=False)
+ >>> logger.debug("My log", main_process_only=True)
+
+ >>> logger = get_logger(__name__, log_level="DEBUG")
+ >>> logger.info("My log")
+ >>> logger.debug("My second log")
+
+ >>> array = ["a", "b", "c", "d"]
+ >>> letter_at_rank = array[accelerator.process_index]
+ >>> logger.info(letter_at_rank, in_order=True)
+ ```
+ """
+ if log_level is None:
+ log_level = os.environ.get("ACCELERATE_LOG_LEVEL", None)
+ logger = logging.getLogger(name)
+ if log_level is not None:
+ logger.setLevel(log_level.upper())
+ logger.root.setLevel(log_level.upper())
+ return MultiProcessAdapter(logger, {})
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/memory_utils.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/memory_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..fa2e2c8b9d7d0064c3e5e282737a7ad6919bde29
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/memory_utils.py
@@ -0,0 +1,22 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import warnings
+
+
+warnings.warn(
+ "memory_utils has been reorganized to utils.memory. Import `find_executable_batchsize` from the main `__init__`: "
+ "`from accelerate import find_executable_batch_size` to avoid this warning.",
+ FutureWarning,
+)
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/optimizer.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/optimizer.py
new file mode 100644
index 0000000000000000000000000000000000000000..c1f8faa15436fb5d1d02ae4d691a4fcac44cd236
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/optimizer.py
@@ -0,0 +1,213 @@
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import inspect
+
+import torch
+
+from .state import AcceleratorState, GradientState
+from .utils import DistributedType, honor_type, is_lomo_available, is_torch_xla_available
+
+
+if is_torch_xla_available():
+ import torch_xla.core.xla_model as xm
+ import torch_xla.runtime as xr
+
+
+def move_to_device(state, device):
+ if isinstance(state, (list, tuple)):
+ return honor_type(state, (move_to_device(t, device) for t in state))
+ elif isinstance(state, dict):
+ return type(state)({k: move_to_device(v, device) for k, v in state.items()})
+ elif isinstance(state, torch.Tensor):
+ return state.to(device)
+ return state
+
+
+class AcceleratedOptimizer(torch.optim.Optimizer):
+ """
+ Internal wrapper around a torch optimizer.
+
+ Conditionally will perform `step` and `zero_grad` if gradients should be synchronized when performing gradient
+ accumulation.
+
+ Args:
+ optimizer (`torch.optim.optimizer.Optimizer`):
+ The optimizer to wrap.
+ device_placement (`bool`, *optional*, defaults to `True`):
+ Whether or not the optimizer should handle device placement. If so, it will place the state dictionary of
+ `optimizer` on the right device.
+ scaler (`torch.amp.GradScaler` or `torch.cuda.amp.GradScaler`, *optional*):
+ The scaler to use in the step function if training with mixed precision.
+ """
+
+ def __init__(self, optimizer, device_placement=True, scaler=None):
+ self.optimizer = optimizer
+ self.scaler = scaler
+ self.accelerator_state = AcceleratorState()
+ self.gradient_state = GradientState()
+ self.device_placement = device_placement
+ self._is_overflow = False
+
+ if self.scaler is not None:
+ self._accelerate_step_called = False
+ self._optimizer_original_step_method = self.optimizer.step
+ self._optimizer_patched_step_method = patch_optimizer_step(self, self.optimizer.step)
+
+ # Handle device placement
+ if device_placement:
+ state_dict = self.optimizer.state_dict()
+ if self.accelerator_state.distributed_type == DistributedType.XLA:
+ xm.send_cpu_data_to_device(state_dict, self.accelerator_state.device)
+ else:
+ state_dict = move_to_device(state_dict, self.accelerator_state.device)
+ self.optimizer.load_state_dict(state_dict)
+
+ @property
+ def state(self):
+ return self.optimizer.state
+
+ @state.setter
+ def state(self, state):
+ self.optimizer.state = state
+
+ @property
+ def param_groups(self):
+ return self.optimizer.param_groups
+
+ @param_groups.setter
+ def param_groups(self, param_groups):
+ self.optimizer.param_groups = param_groups
+
+ @property
+ def defaults(self):
+ return self.optimizer.defaults
+
+ @defaults.setter
+ def defaults(self, defaults):
+ self.optimizer.defaults = defaults
+
+ def add_param_group(self, param_group):
+ self.optimizer.add_param_group(param_group)
+
+ def load_state_dict(self, state_dict):
+ if self.accelerator_state.distributed_type == DistributedType.XLA and self.device_placement:
+ xm.send_cpu_data_to_device(state_dict, self.accelerator_state.device)
+ self.optimizer.load_state_dict(state_dict)
+
+ def state_dict(self):
+ return self.optimizer.state_dict()
+
+ def zero_grad(self, set_to_none=None):
+ if self.gradient_state.sync_gradients:
+ accept_arg = "set_to_none" in inspect.signature(self.optimizer.zero_grad).parameters
+ if accept_arg:
+ if set_to_none is None:
+ set_to_none = True
+ self.optimizer.zero_grad(set_to_none=set_to_none)
+ else:
+ if set_to_none is not None:
+ raise ValueError("`set_to_none` for Optimizer.zero_grad` is not supported by this optimizer.")
+ self.optimizer.zero_grad()
+
+ def train(self):
+ """
+ Sets the optimizer to "train" mode. Useful for optimizers like `schedule_free`
+ """
+ if hasattr(self.optimizer, "train") and callable(self.optimizer.train):
+ self.optimizer.train()
+ elif (
+ hasattr(self.optimizer, "optimizer")
+ and hasattr(self.optimizer.optimizer, "train")
+ and callable(self.optimizer.optimizer.train)
+ ):
+ # the deepspeed optimizer further wraps the optimizer
+ self.optimizer.optimizer.train()
+
+ def eval(self):
+ """
+ Sets the optimizer to "eval" mode. Useful for optimizers like `schedule_free`
+ """
+ if hasattr(self.optimizer, "eval") and callable(self.optimizer.eval):
+ self.optimizer.eval()
+
+ def step(self, closure=None):
+ if is_lomo_available():
+ from lomo_optim import AdaLomo, Lomo
+
+ if (
+ not self.gradient_state.is_xla_gradients_synced
+ and self.accelerator_state.distributed_type == DistributedType.XLA
+ ):
+ gradients = xm._fetch_gradients(self.optimizer)
+ xm.all_reduce("sum", gradients, scale=1.0 / xr.world_size())
+ self.gradient_state.is_xla_gradients_synced = True
+
+ if is_lomo_available():
+ # `step` should be a no-op for LOMO optimizers.
+ if isinstance(self.optimizer, (Lomo, AdaLomo)):
+ return
+
+ if self.gradient_state.sync_gradients:
+ if self.scaler is not None:
+ self.optimizer.step = self._optimizer_patched_step_method
+
+ self.scaler.step(self.optimizer, closure)
+ self.scaler.update()
+
+ if not self._accelerate_step_called:
+ # If the optimizer step was skipped, gradient overflow was detected.
+ self._is_overflow = True
+ else:
+ self._is_overflow = False
+ # Reset the step method to the original one
+ self.optimizer.step = self._optimizer_original_step_method
+ # Reset the indicator
+ self._accelerate_step_called = False
+ else:
+ self.optimizer.step(closure)
+ if self.accelerator_state.distributed_type == DistributedType.XLA:
+ self.gradient_state.is_xla_gradients_synced = False
+
+ def _switch_parameters(self, parameters_map):
+ for param_group in self.optimizer.param_groups:
+ param_group["params"] = [parameters_map.get(p, p) for p in param_group["params"]]
+
+ @property
+ def step_was_skipped(self):
+ """Whether or not the optimizer step was skipped."""
+ return self._is_overflow
+
+ def __getstate__(self):
+ _ignored_keys = [
+ "_accelerate_step_called",
+ "_optimizer_original_step_method",
+ "_optimizer_patched_step_method",
+ ]
+ return {k: v for k, v in self.__dict__.items() if k not in _ignored_keys}
+
+ def __setstate__(self, state):
+ self.__dict__.update(state)
+ if self.scaler is not None:
+ self._accelerate_step_called = False
+ self._optimizer_original_step_method = self.optimizer.step
+ self._optimizer_patched_step_method = patch_optimizer_step(self, self.optimizer.step)
+
+
+def patch_optimizer_step(accelerated_optimizer: AcceleratedOptimizer, method):
+ def patched_step(*args, **kwargs):
+ accelerated_optimizer._accelerate_step_called = True
+ return method(*args, **kwargs)
+
+ return patched_step
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/parallelism_config.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/parallelism_config.py
new file mode 100644
index 0000000000000000000000000000000000000000..0869d0aca232407f1891e2d8109eb33026c9c9d2
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/parallelism_config.py
@@ -0,0 +1,378 @@
+#
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import os
+import warnings
+from dataclasses import dataclass
+from typing import TYPE_CHECKING, Literal, Optional, Union
+
+from accelerate.utils.dataclasses import (
+ DeepSpeedSequenceParallelConfig,
+ DistributedType,
+ TorchContextParallelConfig,
+ TorchTensorParallelConfig,
+)
+from accelerate.utils.versions import is_torch_version
+
+
+if TYPE_CHECKING:
+ from accelerate import Accelerator
+
+
+@dataclass
+class ParallelismConfig:
+ """
+ A dataclass to configure parallelisms applied to the model. Inspired by torchtitan's `ParallelDims`
+ https://github.com/pytorch/torchtitan/blob/main/torchtitan/distributed/parallel_dims.py
+
+ Args:
+ dp_replicate_size (`int`, defaults to `1`):
+ The size of the data parallel group. If `dp_replicate_size` is set to 1, the data parallel replication
+ group will not be used.
+ dp_shard_size (`int`, defaults to `1`):
+ The size of the model shard group. If `dp_replicate_size > 1` and `tp_size > 1`, `dp_shard_size` must also
+ be greater than 1, as composing DDP + TP is currently not supported.
+ tp_size (`int`, defaults to `1`):
+ The size of the tensor parallel group. If `tp_size` is set to `1`, the tensor parallel group will not be
+ used.
+ tp_handler (`~utils.TorchTensorParallelConfig`, defaults to `None`):
+ The handler for the tensor parallel group.
+ cp_size (`int`, defaults to `1`):
+ The size of the context parallel group. Currently not supported, but reserved for future use and enabled
+ for downstream libraries.
+ cp_backend (`str`, defaults to `torch`):
+ Which CP backend to use: `torch` (FSDP2)
+ sp_size (`int`, defaults to `1`):
+ The size of the sequence parallel group.
+ sp_backend (`str`, defaults to `deepspeed`):
+ Which SP backend to use:`deepspeed` (ALST/Ulysses)
+
+ You may obtain different distributed data parallel paradigms by configuring `dp_replicate_size` and `dp_shard_size`
+ together:
+ - `dp_replicate_size == 1` and `dp_shard_size > 1`, we obtain Fully Sharded Data Parallel (FSDP).
+ - `dp_replicate_size > 1` and `dp_shard_size > 1`, we obtain Hybrid Sharded Data Parallel (HSDP).
+ - `dp_replicate_size > 1` and `dp_shard_size == 1` is an invalid configuration, to use pure DP, use
+ `DistributedDataParallelKwargs` instead.
+
+ """
+
+ dp_replicate_size: Optional[int] = None
+ dp_shard_size: Optional[int] = None
+ tp_size: Optional[int] = None
+ cp_size: Optional[int] = None
+ cp_backend: Literal["torch"] = None
+ sp_size: Optional[int] = None
+ sp_backend: Literal["deepspeed"] = None
+
+ # we use Union because we might support other x parallel plugins (i.e. deepspeed, etc)
+ tp_handler: Union[None, TorchTensorParallelConfig] = None
+ cp_handler: Union[None, TorchContextParallelConfig] = None
+ sp_handler: Union[None, DeepSpeedSequenceParallelConfig] = None
+
+ device_mesh = None
+
+ def __repr__(self):
+ return (
+ "ParallelismConfig(\n "
+ f"\tdp_replicate_size={self.dp_replicate_size},\n"
+ f"\tdp_shard_size={self.dp_shard_size},\n"
+ f"\ttp_size={self.tp_size},\n"
+ f"\tcp_size={self.cp_size},\n"
+ f"\tcp_backend={self.cp_backend},\n"
+ f"\tsp_size={self.sp_size},\n"
+ f"\tsp_backend={self.sp_backend},\n"
+ f"\ttotal_size={self.total_size}\n"
+ f"\ttp_handler={self.tp_handler},\n"
+ f"\tcp_handler={self.cp_handler})\n"
+ )
+
+ def to_json(self):
+ import copy
+
+ _non_serializable_fields = ["device_mesh"]
+
+ copy.deepcopy(
+ {
+ k: copy.deepcopy(v.__dict__) if hasattr(v, "__dict__") else v
+ for k, v in self.__dict__.items()
+ if k not in _non_serializable_fields
+ }
+ )
+
+ @property
+ def dp_dim_names(self):
+ """Names of enabled dimensions across which data parallelism is applied."""
+ dims = []
+ if self.dp_replicate_enabled:
+ dims += ["dp_replicate"]
+ if self.dp_shard_enabled:
+ dims += ["dp_shard"]
+ return dims
+
+ @property
+ def non_dp_dim_names(self):
+ """Names of enabled dimensions which will receive the same batch (non-data parallel dimensions)."""
+ dims = []
+ if self.tp_enabled:
+ dims += ["tp"]
+ if self.cp_enabled:
+ dims += ["cp"]
+ if self.sp_enabled:
+ dims += ["sp"]
+ return dims
+
+ @property
+ def dp_shard_cp_dim_names(self):
+ """Names of enabled dimensions which will be flattened into a joint mesh across which is model sharded in FSDP."""
+ dims = []
+ if self.dp_shard_enabled:
+ dims += ["dp_shard"]
+ if self.cp_enabled:
+ dims += ["cp"]
+ return dims
+
+ @property
+ def dp_cp_dim_names(self):
+ """Names of enabled dimensions across which loss should be averaged"""
+ dims = []
+ if self.dp_replicate_enabled:
+ dims += ["dp_replicate"]
+ if self.dp_shard_enabled:
+ dims += ["dp_shard"]
+ if self.cp_enabled:
+ dims += ["cp"]
+ return dims
+
+ @property
+ def fsdp_dim_names(self):
+ """Names of enabled dimensions across which FSDP is applied, including data parallel replication."""
+ dims = []
+ if self.dp_replicate_enabled:
+ dims += ["dp_replicate"]
+ dims += ["dp_shard_cp"]
+ return dims
+
+ @property
+ def total_size(self):
+ """The total size of the parallelism configuration, which is the product of all sizes."""
+ return self.dp_replicate_size * self.dp_shard_size * self.tp_size * self.cp_size * self.sp_size
+
+ @property
+ def non_data_parallel_size(self):
+ """The size of the non-data parallel dimensions, which is the product of tensor and context parallel sizes."""
+ return self.tp_size * self.cp_size * self.sp_size
+
+ @property
+ def data_parallel_size(self):
+ """The size of the data parallel dimensions, which is the product of data parallel replication and"""
+ return self.dp_replicate_size * self.dp_shard_size
+
+ @property
+ def dp_replicate_enabled(self):
+ """True if data parallel replication is enabled, i.e. `dp_replicate_size > 1`."""
+ return self.dp_replicate_size > 1
+
+ @property
+ def dp_shard_enabled(self):
+ """True if data parallel sharding is enabled, i.e. `dp_shard_size > 1`."""
+ return self.dp_shard_size > 1
+
+ @property
+ def tp_enabled(self):
+ """True if tensor parallelism is enabled, i.e. `tp_size > 1`."""
+ return self.tp_size > 1
+
+ @property
+ def cp_enabled(self):
+ """True if context parallelism is enabled, i.e. `cp_size > 1`."""
+ return self.cp_size > 1
+
+ @property
+ def sp_enabled(self):
+ """True if context parallelism is enabled, i.e. `sp_size > 1`."""
+ return self.sp_size > 1
+
+ @property
+ def active_mesh_dims(self):
+ """Names of all active mesh dimensions."""
+ return self.dp_dim_names + self.non_dp_dim_names
+
+ def build_device_mesh(self, device_type: str):
+ """Builds a device mesh for the given device type based on the parallelism configuration.
+ This method will also create required joint meshes (e.g. `dp_shard_cp`, `dp_cp`, `dp`).
+
+ Args:
+ device_type (`str`): The type of device for which to build the mesh, e
+ """
+ if is_torch_version(">=", "2.2.0"):
+ from torch.distributed.device_mesh import init_device_mesh
+ else:
+ raise RuntimeError("Building a device_mesh requires to have torch>=2.2.0")
+
+ mesh = self._get_mesh()
+ if len(mesh) == 0:
+ return None
+ mesh_dim_names, mesh_shape = mesh
+ device_mesh = init_device_mesh(
+ device_type,
+ mesh_shape,
+ mesh_dim_names=mesh_dim_names,
+ )
+ if self.dp_dim_names:
+ device_mesh[self.dp_dim_names]._flatten("dp")
+ if self.dp_shard_cp_dim_names:
+ device_mesh[self.dp_shard_cp_dim_names]._flatten("dp_shard_cp")
+ if self.dp_cp_dim_names:
+ device_mesh[self.dp_cp_dim_names]._flatten("dp_cp")
+
+ return device_mesh
+
+ def get_device_mesh(self, device_type: Optional[str] = None):
+ if self.device_mesh is None:
+ if device_type is not None:
+ self.device_mesh = self.build_device_mesh(device_type)
+ else:
+ raise ("You need to pass a device_type e.g cuda to build the device mesh")
+ else:
+ if device_type is not None:
+ if self.device_mesh.device_type != device_type:
+ raise ValueError(
+ f"The device_mesh is already created with device type {self.device_mesh.device_type}. However, you are trying to get a device mesh with device_type {device_type}. Please check if you correctly initialized your device_mesh"
+ )
+ return self.device_mesh
+
+ def _get_mesh(self) -> tuple[tuple[int, ...], tuple[str, ...]]:
+ """Generate mesh shape and dimension names for torch.distributed.init_device_mesh()."""
+
+ # Build mesh dimensions dictionary
+ mesh_dims = {parallelism: self._sizes[parallelism] for parallelism in self.active_mesh_dims}
+
+ # Apply canonical ordering
+ mesh_order = ["dp_replicate", "dp_shard", "cp", "sp", "tp"]
+ sorted_items = sorted(
+ mesh_dims.items(),
+ key=lambda x: (mesh_order.index(x[0])),
+ )
+ return tuple(zip(*sorted_items))
+
+ def __post_init__(self):
+ # Basic size validation
+ if self.dp_replicate_size is None:
+ self.dp_replicate_size = int(os.environ.get("PARALLELISM_CONFIG_DP_REPLICATE_SIZE", "1"))
+ if self.dp_shard_size is None:
+ self.dp_shard_size = int(os.environ.get("PARALLELISM_CONFIG_DP_SHARD_SIZE", "1"))
+ if self.tp_size is None:
+ self.tp_size = int(os.environ.get("PARALLELISM_CONFIG_TP_SIZE", "1"))
+ if self.cp_size is None:
+ self.cp_size = int(os.environ.get("PARALLELISM_CONFIG_CP_SIZE", "1"))
+ if self.cp_backend is None:
+ self.cp_backend = os.environ.get("PARALLELISM_CONFIG_CP_BACKEND", "torch")
+ if self.sp_size is None:
+ self.sp_size = int(os.environ.get("PARALLELISM_CONFIG_SP_SIZE", "1"))
+ if self.sp_backend is None:
+ self.sp_backend = os.environ.get("PARALLELISM_CONFIG_SP_BACKEND", "deepspeed")
+
+ if self.tp_size > 1:
+ if self.tp_handler is None:
+ self.tp_handler = TorchTensorParallelConfig()
+
+ if self.cp_size > 1:
+ if self.cp_handler is None:
+ self.cp_handler = TorchContextParallelConfig()
+ else:
+ cp_backends_config_map = dict(
+ torch=TorchContextParallelConfig,
+ )
+ if not isinstance(self.cp_handler, cp_backends_config_map[self.cp_backend]):
+ raise ValueError(
+ f"ParallelismConfig's cp_backend={self.cp_backend} requires {cp_backends_config_map[self.cp_backend]}, but cp_handler was set to {type(self.cp_handler)}"
+ )
+
+ if self.sp_size > 1:
+ if self.sp_handler is None:
+ self.sp_handler = DeepSpeedSequenceParallelConfig()
+ if self.dp_replicate_size < 1:
+ raise ValueError(f"dp_replicate_size must be at least 1, but got {self.dp_replicate_size}")
+ if self.dp_shard_size < 1:
+ raise ValueError(f"dp_shard_size must be at least 1, but got {self.dp_shard_size}")
+ if self.tp_size < 1:
+ raise ValueError(f"tp_size must be at least 1, but got {self.tp_size}")
+ if self.cp_size < 1:
+ raise ValueError(f"cp_size must be at least 1, but got {self.cp_size}")
+ valid_cp_backends = ["torch"]
+ if self.cp_backend not in valid_cp_backends:
+ raise ValueError(f"cp_backend must be one of {valid_cp_backends}, but got {self.cp_backend}")
+
+ if self.sp_size < 1:
+ raise ValueError(f"sp_size must be at least 1, but got {self.sp_size}")
+ valid_sp_backends = ["deepspeed"]
+ if self.sp_backend not in valid_sp_backends:
+ raise ValueError(f"sp_backend must be one of {valid_sp_backends}, but got {self.sp_backend}")
+
+ if (self.tp_size > 1 or self.cp_size > 1) and self.dp_replicate_size > 1 and self.dp_shard_size == 1:
+ raise ValueError(
+ "Tensor/Context parallelism (tp/cp_size > 1) cannot be used with pure data parallelism (dp_replicate_size > 1 and dp_shard_size == 1). "
+ "Please set dp_shard_size > 1 and dp_replicate_size == 1 to compose FSDP + TP/CP for 2D parallel, "
+ "or set dp_replicate_size == 1 and dp_shard_size > 1 to compose HSDP + TP/CP for 3D parallel."
+ )
+ self._sizes = {
+ "dp_replicate": self.dp_replicate_size,
+ "dp_shard": self.dp_shard_size,
+ "tp": self.tp_size,
+ "cp": self.cp_size,
+ "sp": self.sp_size,
+ }
+
+ def _set_size(self, parallelism: str, size: int):
+ assert parallelism in self._sizes.keys(), f"Parallelism must be one of {self._sizes.keys()}"
+ self._sizes[parallelism] = size
+ setattr(self, f"{parallelism}_size", size)
+
+ def _validate_accelerator(self, accelerator: "Accelerator"):
+ _warnings = set()
+ if not accelerator.multi_device and self.total_size == 1:
+ # No distributed setup, valid parallelism config
+ return
+
+ # We need this to ensure DDP works
+ if self.total_size == 1:
+ self._set_size("dp_replicate", accelerator.num_processes)
+
+ if self.total_size != accelerator.num_processes:
+ raise ValueError(
+ f"ParallelismConfig total_size ({self.total_size}) does not match "
+ f"num_processes ({accelerator.num_processes}). Please adjust dp_replicate_size/ "
+ f"dp_shard_size/tp_size/cp_size/sp_size."
+ )
+
+ if self.total_size > 1 and not (
+ accelerator.is_fsdp2
+ or accelerator.multi_device
+ or accelerator.distributed_type == DistributedType.DEEPSPEED
+ ):
+ raise ValueError(
+ f"ParallelismConfig is only compatible DistributedType.FSDP (version 2) or DistributedType.Multi{{Device}} or DistributedType.DEEPSPEED, but got {accelerator.distributed_type}."
+ )
+
+ for parallelism, size in self._sizes.items():
+ if size == 1 and getattr(self, f"{parallelism}_handler", None) is not None:
+ _warnings.add(
+ f"ParallelismConfig.{parallelism}_handler is set, but {parallelism}_size is set to 1. This handler will be ignored."
+ )
+
+ if _warnings and accelerator.is_main_process:
+ warnings.warn(
+ "ParallelismConfig has the following warnings:\n" + "\n".join(_warnings),
+ UserWarning,
+ )
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/scheduler.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/scheduler.py
new file mode 100644
index 0000000000000000000000000000000000000000..1fa8a13f238afd7b908ee8e8cb8e0620f48d4ff8
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/scheduler.py
@@ -0,0 +1,98 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+# We ignore warnings about stepping the scheduler since we step it ourselves during gradient accumulation
+
+import warnings
+
+from .state import AcceleratorState, GradientState
+
+
+warnings.filterwarnings("ignore", category=UserWarning, module="torch.optim.lr_scheduler")
+
+
+class AcceleratedScheduler:
+ """
+ A wrapper around a learning rate scheduler that will only step when the optimizer(s) have a training step. Useful
+ to avoid making a scheduler step too fast when gradients went overflow and there was no training step (in mixed
+ precision training)
+
+ When performing gradient accumulation scheduler lengths should not be changed accordingly, Accelerate will always
+ step the scheduler to account for it.
+
+ Args:
+ scheduler (`torch.optim.lr_scheduler._LRScheduler`):
+ The scheduler to wrap.
+ optimizers (one or a list of `torch.optim.Optimizer`):
+ The optimizers used.
+ step_with_optimizer (`bool`, *optional*, defaults to `True`):
+ Whether or not the scheduler should be stepped at each optimizer step.
+ split_batches (`bool`, *optional*, defaults to `False`):
+ Whether or not the dataloaders split one batch across the different processes (so batch size is the same
+ regardless of the number of processes) or create batches on each process (so batch size is the original
+ batch size multiplied by the number of processes).
+ """
+
+ def __init__(self, scheduler, optimizers, step_with_optimizer: bool = True, split_batches: bool = False):
+ self.scheduler = scheduler
+ self.optimizers = optimizers if isinstance(optimizers, (list, tuple)) else [optimizers]
+ self.split_batches = split_batches
+ self.step_with_optimizer = step_with_optimizer
+ self.gradient_state = GradientState()
+
+ def step(self, *args, **kwargs):
+ if not self.step_with_optimizer:
+ # No link between scheduler and optimizer -> just step
+ self.scheduler.step(*args, **kwargs)
+ return
+
+ # Otherwise, first make sure the optimizer was stepped.
+ if not self.gradient_state.sync_gradients:
+ if self.gradient_state.adjust_scheduler:
+ self.scheduler._step_count += 1
+ return
+
+ for opt in self.optimizers:
+ if opt.step_was_skipped:
+ return
+ if self.split_batches:
+ # Split batches -> the training dataloader batch size is not changed so one step per training step
+ self.scheduler.step(*args, **kwargs)
+ else:
+ # Otherwise the training dataloader batch size was multiplied by `num_processes`, so we need to do
+ # num_processes steps per training step
+ num_processes = AcceleratorState().num_processes
+ for _ in range(num_processes):
+ # Special case when using OneCycle and `drop_last` was not used
+ if hasattr(self.scheduler, "total_steps"):
+ if self.scheduler._step_count <= self.scheduler.total_steps:
+ self.scheduler.step(*args, **kwargs)
+ else:
+ self.scheduler.step(*args, **kwargs)
+
+ # Passthroughs
+ def get_last_lr(self):
+ return self.scheduler.get_last_lr()
+
+ def state_dict(self):
+ return self.scheduler.state_dict()
+
+ def load_state_dict(self, state_dict):
+ self.scheduler.load_state_dict(state_dict)
+
+ def get_lr(self):
+ return self.scheduler.get_lr()
+
+ def print_lr(self, *args, **kwargs):
+ return self.scheduler.print_lr(*args, **kwargs)
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/state.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/state.py
new file mode 100644
index 0000000000000000000000000000000000000000..4da3c91f3c29275eb109d5116b7dd07bd88a29f6
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/state.py
@@ -0,0 +1,1373 @@
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import annotations
+
+import logging
+import os
+import threading
+import warnings
+import weakref
+from contextlib import contextmanager
+from functools import partial
+from typing import Any, Callable
+
+import torch
+
+from .utils import (
+ DistributedType,
+ DynamoBackend,
+ GradientAccumulationPlugin,
+ check_cuda_fp8_capability,
+ check_cuda_p2p_ib_support,
+ deepspeed_required,
+ get_cpu_distributed_information,
+ get_int_from_env,
+ is_ccl_available,
+ is_datasets_available,
+ is_deepspeed_available,
+ is_fp8_available,
+ is_habana_gaudi1,
+ is_hpu_available,
+ is_ipex_available,
+ is_mlu_available,
+ is_mps_available,
+ is_musa_available,
+ is_npu_available,
+ is_sdaa_available,
+ is_torch_xla_available,
+ is_xccl_available,
+ is_xpu_available,
+ parse_choice_from_env,
+ parse_flag_from_env,
+ set_numa_affinity,
+)
+from .utils.dataclasses import SageMakerDistributedType
+
+
+if is_torch_xla_available():
+ import torch_xla.core.xla_model as xm
+ import torch_xla.runtime as xr
+
+if is_mlu_available(check_device=False):
+ import torch_mlu # noqa: F401
+
+if is_sdaa_available(check_device=False):
+ import torch_sdaa # noqa: F401
+
+if is_musa_available(check_device=False):
+ import torch_musa # noqa: F401
+
+if is_npu_available(check_device=False):
+ import torch_npu # noqa: F401
+
+
+logger = logging.getLogger(__name__)
+
+
+def is_initialized() -> bool:
+ """
+ Checks if the `AcceleratorState` has been initialized from `Accelerator`. Same as `AcceleratorState.initialized`,
+ but works as a module method.
+ """
+ return AcceleratorState._shared_state != {}
+
+
+# Lambda function that does nothing
+def do_nothing(*args, **kwargs):
+ return None
+
+
+class ThreadLocalSharedDict(threading.local):
+ """
+ Descriptor that holds a dict shared between instances of a class in the same thread.
+
+ Note: Descriptors have slightly different semantics than just a dict field on its own.
+ `PartialState(...)._shared_state` and `PartialState._shared_state` (instance vs class) give the same value: the
+ underlying _storage dict. Likewise, `PartialState(...)._shared_state = {...}` overrides the _storage dict inside
+ the descriptor as you would expect. However, `PartialState._shared_state = {}` actually replaces the descriptor
+ object with a dict instead Thus, you should modify the _storage dict in-place (e.g. `_shared_state.clear()`).
+
+ See Python documentation for an explanation of descriptors: https://docs.python.org/3/howto/descriptor.html
+
+ This is required for using PyTorch/XLA with PJRT in multithreaded mode (required for TPU v2 and v3).
+
+ See https://github.com/pytorch/xla/blob/r2.0/docs/pjrt.md#multithreading-on-tpu-v2v3
+ """
+
+ def __init__(self, thread_local: bool = False):
+ self._storage = {}
+
+ def __get__(self, obj, objtype=None):
+ return self._storage
+
+ def __set__(self, obj, value):
+ self._storage = value
+
+
+# Prefer global shared dictionary, except when using TPU.
+SharedDict = dict if not is_torch_xla_available() else ThreadLocalSharedDict
+
+
+# Inspired by Alex Martelli's 'Borg'.
+class PartialState:
+ """
+ Singleton class that has information about the current training environment and functions to help with process
+ control. Designed to be used when only process control and device execution states are needed. Does *not* need to
+ be initialized from `Accelerator`.
+
+ Args:
+ cpu (`bool`, *optional*):
+ Whether or not to force the script to execute on CPU. Will ignore any accelerators available if set to
+ `True` and force the execution on the CPU.
+ kwargs (additional keyword arguments, *optional*):
+ Additional keyword arguments to pass to the relevant `init_process_group` function. Valid `kwargs` can be
+ found in [`utils.InitProcessGroupKwargs`]. See the example section for detailed usage.
+
+ **Available attributes:**
+
+ - **device** (`torch.device`) -- The device to use.
+ - **distributed_type** ([`~accelerate.state.DistributedType`]) -- The type of distributed environment currently
+ in use.
+ - **local_process_index** (`int`) -- The index of the current process on the current server.
+ - **mixed_precision** (`str`) -- Whether or not the current script will use mixed precision, and if so the type
+ of mixed precision being performed. (Choose from 'no','fp16','bf16 or 'fp8').
+ - **num_processes** (`int`) -- The number of processes currently launched in parallel.
+ - **process_index** (`int`) -- The index of the current process.
+ - **is_last_process** (`bool`) -- Whether or not the current process is the last one.
+ - **is_main_process** (`bool`) -- Whether or not the current process is the main one.
+ - **is_local_main_process** (`bool`) -- Whether or not the current process is the main one on the local node.
+ - **debug** (`bool`) -- Whether or not the current script is being run in debug mode.
+
+ Example:
+ ```python
+ from accelerate.utils import InitProcessGroupKwargs
+
+ # To include `InitProcessGroupKwargs`, init then call `.to_kwargs()`
+ kwargs = InitProcessGroupKwargs(...).to_kwargs()
+ state = PartialState(**kwargs)
+ ```
+ """
+
+ _shared_state = SharedDict()
+ _known_attrs = [
+ "_cpu",
+ "_mixed_precision",
+ "_shared_state",
+ "backend",
+ "debug",
+ "device",
+ "distributed_type",
+ "fork_launched",
+ "local_process_index",
+ "num_processes",
+ "process_index",
+ ]
+
+ def __init__(self, cpu: bool = False, **kwargs):
+ self.__dict__ = self._shared_state
+ if not self.initialized:
+ self._cpu = cpu
+ self.backend = None
+ env_device = os.environ.get("ACCELERATE_TORCH_DEVICE", None)
+ self.device = torch.device(env_device) if env_device is not None else None
+ self.debug = parse_flag_from_env("ACCELERATE_DEBUG_MODE")
+ use_sagemaker_dp = kwargs.pop("_use_sagemaker_dp", None)
+ dist_information = None
+ if use_sagemaker_dp is None:
+ use_sagemaker_dp = (
+ os.environ.get("ACCELERATE_USE_SAGEMAKER", "false").lower() == "true"
+ and os.environ.get("ACCELERATE_SAGEMAKER_DISTRIBUTED_TYPE") != SageMakerDistributedType.NO
+ )
+
+ # Sets up self.backend + imports
+ original_backend = kwargs.pop("backend", None)
+ backend, distributed_type = self._prepare_backend(cpu, use_sagemaker_dp, original_backend)
+ if original_backend is not None and backend != original_backend:
+ raise ValueError(f"Your assigned backend {original_backend} is not available, please use {backend}")
+ self.backend = backend
+ self.distributed_type = distributed_type
+ use_deepspeed = False
+ if not cpu and self.backend != "xla":
+ if int(os.environ.get("LOCAL_RANK", -1)) != -1:
+ # Deal with spawning deepspeed
+ if os.environ.get("ACCELERATE_USE_DEEPSPEED", "false").lower() == "true":
+ if not is_deepspeed_available():
+ raise ImportError(
+ "DeepSpeed is not available => install it using `pip3 install deepspeed` or build it from source"
+ )
+ from deepspeed import comm as dist
+
+ if not dist.is_initialized():
+ if self.backend == "tccl":
+ local_rank = os.environ.get("LOCAL_RANK", -1)
+ torch.sdaa.set_device(f"sdaa:{local_rank}")
+ dist.init_distributed(dist_backend=self.backend, auto_mpi_discovery=False, **kwargs)
+ # We need to flag to `use_deepspeed` to be True to override `distributed_type` later
+ use_deepspeed = True
+ # Deal with all other backends but XPU and CPU, that gets handled special later
+ elif (
+ self.distributed_type not in (DistributedType.MULTI_XPU, DistributedType.MULTI_CPU)
+ and not torch.distributed.is_initialized()
+ ):
+ if self.backend == "tccl":
+ local_rank = os.environ.get("LOCAL_RANK", -1)
+ torch.sdaa.set_device(f"sdaa:{local_rank}")
+ if (
+ self.backend == "nccl"
+ and os.environ.get("ACCELERATE_USE_FSDP", "false").lower() == "true"
+ and (
+ os.environ.get("FSDP_OFFLOAD_PARAMS", "false").lower() == "true"
+ or os.environ.get("FSDP_STATE_DICT_TYPE", "SHARDED_STATE_DICT") == "FULL_STATE_DICT"
+ )
+ ):
+ self.backend = "cuda:nccl,cpu:gloo"
+ torch.distributed.init_process_group(backend=self.backend, **kwargs)
+
+ # XPU and CPU require special env configs to be set
+ if self.distributed_type in (DistributedType.MULTI_XPU, DistributedType.MULTI_CPU):
+ dist_information = get_cpu_distributed_information()
+ os.environ["RANK"] = str(dist_information.rank)
+ os.environ["WORLD_SIZE"] = str(dist_information.world_size)
+ os.environ["LOCAL_RANK"] = str(dist_information.local_rank)
+ os.environ["LOCAL_WORLD_SIZE"] = str(dist_information.local_world_size)
+ if not os.environ.get("MASTER_PORT", None):
+ os.environ["MASTER_PORT"] = "29500"
+ if (
+ not os.environ.get("MASTER_ADDR", None)
+ and dist_information.local_world_size != dist_information.world_size
+ and self.backend != "mpi"
+ ):
+ raise ValueError(
+ "Tried to launch on distributed with multinode, but `MASTER_ADDR` env was not set, "
+ "please try exporting rank 0's hostname as `MASTER_ADDR`"
+ )
+ kwargs["rank"] = dist_information.rank
+ kwargs["world_size"] = dist_information.world_size
+
+ if (
+ self.distributed_type == DistributedType.MULTI_CPU
+ and get_int_from_env(["OMP_NUM_THREADS"], 0) == 0
+ ):
+ import psutil
+
+ num_cpu_threads_per_process = int(
+ psutil.cpu_count(logical=False) / dist_information.local_world_size
+ )
+ if num_cpu_threads_per_process == 0:
+ num_cpu_threads_per_process = 1
+ torch.set_num_threads(num_cpu_threads_per_process)
+ warnings.warn(
+ f"OMP_NUM_THREADS/MKL_NUM_THREADS unset, we set it at {num_cpu_threads_per_process} to improve oob"
+ " performance."
+ )
+
+ if not torch.distributed.is_initialized():
+ torch.distributed.init_process_group(backend=self.backend, **kwargs)
+
+ # No backend == no distributed training
+ if self.backend is None:
+ self.distributed_type = DistributedType.NO
+ self.num_processes = 1
+ self.process_index = 0
+ self.local_process_index = 0
+ elif self.backend == "xla":
+ # XLA needs device setting first for `set_replication`
+ self.set_device()
+ xm.set_replication(self.device, xm.get_xla_supported_devices())
+ self.num_processes = xr.world_size()
+ self.process_index = xr.global_ordinal()
+ if is_torch_xla_available(check_is_tpu=True):
+ self.local_process_index = xm.get_local_ordinal()
+ else:
+ self.local_process_index = int(os.environ.get("LOCAL_RANK", -1))
+ else:
+ self.num_processes = torch.distributed.get_world_size()
+ self.process_index = torch.distributed.get_rank()
+ self.local_process_index = (
+ int(os.environ.get("LOCAL_RANK", -1)) if dist_information is None else dist_information.local_rank
+ )
+ self.set_device()
+ # Now we can change to deepseed
+ if use_deepspeed:
+ self.distributed_type = DistributedType.DEEPSPEED
+
+ # Set CPU affinity if enabled
+ if parse_flag_from_env("ACCELERATE_CPU_AFFINITY", False):
+ set_numa_affinity(self.local_process_index)
+
+ # Check for old RTX 4000's that can't use P2P or IB and are on old drivers
+ if self.device.type == "cuda" and not check_cuda_p2p_ib_support():
+ if "NCCL_P2P_DISABLE" not in os.environ or "NCCL_IB_DISABLE" not in os.environ:
+ raise NotImplementedError(
+ "Using RTX 4000 series doesn't support faster communication broadband via P2P or IB. "
+ 'Please set `NCCL_P2P_DISABLE="1"` and `NCCL_IB_DISABLE="1" or use `accelerate launch` which '
+ "will do this automatically."
+ )
+
+ # Important: This should be the *only* code outside of `self.initialized!`
+ self.fork_launched = parse_flag_from_env("FORK_LAUNCHED", 0)
+
+ def __repr__(self) -> str:
+ return (
+ f"Distributed environment: {self.distributed_type}{(' Backend: ' + self.backend) if self.backend else ''}\n"
+ f"Num processes: {self.num_processes}\n"
+ f"Process index: {self.process_index}\n"
+ f"Local process index: {self.local_process_index}\n"
+ f"Device: {self.device}\n"
+ )
+
+ @staticmethod
+ def _reset_state():
+ "Resets `_shared_state`, is used internally and should not be called"
+ PartialState._shared_state.clear()
+
+ @property
+ def initialized(self) -> bool:
+ "Returns whether the `PartialState` has been initialized"
+ return self._shared_state != {}
+
+ @property
+ def use_distributed(self):
+ """
+ Whether the Accelerator is configured for distributed training
+ """
+ return self.distributed_type != DistributedType.NO and self.num_processes > 1
+
+ @property
+ def is_last_process(self) -> bool:
+ "Returns whether the current process is the last one"
+ return self.process_index == self.num_processes - 1
+
+ @property
+ def is_main_process(self) -> bool:
+ "Returns whether the current process is the main process"
+ return (
+ self.process_index == 0 if self.distributed_type != DistributedType.MEGATRON_LM else self.is_last_process
+ )
+
+ @property
+ def is_local_main_process(self) -> bool:
+ "Returns whether the current process is the main process on the local node"
+ return (
+ self.local_process_index == 0
+ if self.distributed_type != DistributedType.MEGATRON_LM
+ else self.is_last_process
+ )
+
+ def wait_for_everyone(self):
+ """
+ Will stop the execution of the current process until every other process has reached that point (so this does
+ nothing when the script is only run in one process). Useful to do before saving a model.
+
+ Example:
+
+ ```python
+ >>> # Assuming two GPU processes
+ >>> import time
+ >>> from accelerate.state import PartialState
+
+ >>> state = PartialState()
+ >>> if state.is_main_process:
+ ... time.sleep(2)
+ >>> else:
+ ... print("I'm waiting for the main process to finish its sleep...")
+ >>> state.wait_for_everyone()
+ >>> # Should print on every process at the same time
+ >>> print("Everyone is here")
+ ```
+ """
+ if self.distributed_type in (
+ DistributedType.MULTI_GPU,
+ DistributedType.MULTI_MLU,
+ DistributedType.MULTI_SDAA,
+ DistributedType.MULTI_MUSA,
+ DistributedType.MULTI_NPU,
+ DistributedType.MULTI_XPU,
+ DistributedType.MULTI_CPU,
+ DistributedType.MULTI_HPU,
+ DistributedType.DEEPSPEED,
+ DistributedType.FSDP,
+ ):
+ torch.distributed.barrier(device_ids=[self.local_process_index])
+ elif self.distributed_type == DistributedType.XLA:
+ xm.rendezvous("accelerate.utils.wait_for_everyone")
+
+ def _goes_first(self, is_main: bool):
+ if not is_main:
+ self.wait_for_everyone()
+
+ yield
+
+ if is_main:
+ self.wait_for_everyone()
+
+ @contextmanager
+ def split_between_processes(self, inputs: list | tuple | dict | torch.Tensor, apply_padding: bool = False):
+ """
+ Splits `input` between `self.num_processes` quickly and can be then used on that process. Useful when doing
+ distributed inference, such as with different prompts.
+
+ Note that when using a `dict`, all keys need to have the same number of elements.
+
+ Args:
+ inputs (`list`, `tuple`, `torch.Tensor`, `dict` of `list`/`tuple`/`torch.Tensor`, or `datasets.Dataset`):
+ The input to split between processes.
+ apply_padding (`bool`, `optional`, defaults to `False`):
+ Whether to apply padding by repeating the last element of the input so that all processes have the same
+ number of elements. Useful when trying to perform actions such as `gather()` on the outputs or passing
+ in less inputs than there are processes. If so, just remember to drop the padded elements afterwards.
+
+
+ Example:
+
+ ```python
+ # Assume there are two processes
+ from accelerate import PartialState
+
+ state = PartialState()
+ with state.split_between_processes(["A", "B", "C"]) as inputs:
+ print(inputs)
+ # Process 0
+ ["A", "B"]
+ # Process 1
+ ["C"]
+
+ with state.split_between_processes(["A", "B", "C"], apply_padding=True) as inputs:
+ print(inputs)
+ # Process 0
+ ["A", "B"]
+ # Process 1
+ ["C", "C"]
+ ```
+ """
+ if self.num_processes == 1:
+ yield inputs
+ return
+ length = len(inputs)
+ # Nested dictionary of any types
+ if isinstance(inputs, dict):
+ length = len(inputs[list(inputs.keys())[0]])
+ if not all(len(v) == length for v in inputs.values()):
+ raise ValueError("All values in the dictionary must have the same length")
+ num_samples_per_process, num_extras = divmod(length, self.num_processes)
+ start_index = self.process_index * num_samples_per_process + min(self.process_index, num_extras)
+ end_index = start_index + num_samples_per_process + (1 if self.process_index < num_extras else 0)
+
+ def _split_values(inputs, start_index, end_index):
+ if isinstance(inputs, (list, tuple, torch.Tensor)):
+ if start_index >= len(inputs):
+ result = inputs[-1:]
+ else:
+ result = inputs[start_index:end_index]
+ if apply_padding:
+ if isinstance(result, torch.Tensor):
+ from accelerate.utils import pad_across_processes, send_to_device
+
+ # The tensor needs to be on the device before we can pad it
+ tensorized_result = send_to_device(result, self.device)
+ result = pad_across_processes(tensorized_result, pad_index=inputs[-1])
+ else:
+ result += [result[-1]] * (num_samples_per_process + (1 if num_extras > 0 else 0) - len(result))
+ return result
+ elif isinstance(inputs, dict):
+ for key in inputs.keys():
+ inputs[key] = _split_values(inputs[key], start_index, end_index)
+ return inputs
+ else:
+ if is_datasets_available():
+ from datasets import Dataset
+
+ if isinstance(inputs, Dataset):
+ if start_index >= len(inputs):
+ start_index = len(inputs) - 1
+ if end_index > len(inputs):
+ end_index = len(inputs)
+ result_idcs = list(range(start_index, end_index))
+ if apply_padding:
+ result_idcs += [end_index - 1] * (
+ num_samples_per_process + (1 if num_extras > 0 else 0) - len(result_idcs)
+ )
+ return inputs.select(result_idcs)
+ return inputs
+
+ yield _split_values(inputs, start_index, end_index)
+
+ @contextmanager
+ def main_process_first(self):
+ """
+ Lets the main process go first inside a with block.
+
+ The other processes will enter the with block after the main process exits.
+
+ Example:
+
+ ```python
+ >>> from accelerate import Accelerator
+
+ >>> accelerator = Accelerator()
+ >>> with accelerator.main_process_first():
+ ... # This will be printed first by process 0 then in a seemingly
+ ... # random order by the other processes.
+ ... print(f"This will be printed by process {accelerator.process_index}")
+ ```
+ """
+ yield from self._goes_first(self.is_main_process)
+
+ @contextmanager
+ def local_main_process_first(self):
+ """
+ Lets the local main process go inside a with block.
+
+ The other processes will enter the with block after the main process exits.
+
+ Example:
+
+ ```python
+ >>> from accelerate.state import PartialState
+
+ >>> state = PartialState()
+ >>> with state.local_main_process_first():
+ ... # This will be printed first by local process 0 then in a seemingly
+ ... # random order by the other processes.
+ ... print(f"This will be printed by process {state.local_process_index}")
+ ```
+ """
+ yield from self._goes_first(self.is_local_main_process)
+
+ def on_main_process(self, function: Callable[..., Any] | None = None):
+ """
+ Decorator that only runs the decorated function on the main process.
+
+ Args:
+ function (`Callable`): The function to decorate.
+
+ Example:
+
+ ```python
+ >>> from accelerate.state import PartialState
+
+ >>> state = PartialState()
+
+
+ >>> @state.on_main_process
+ ... def print_something():
+ ... print("This will be printed by process 0 only.")
+
+
+ >>> print_something()
+ "This will be printed by process 0 only"
+ ```
+ """
+ if not self.initialized:
+ raise ValueError("The `PartialState` or `Accelerator` must be initialized before calling this function.")
+ if self.is_main_process or not self.use_distributed:
+ return function
+ return do_nothing
+
+ def on_local_main_process(self, function: Callable[..., Any] | None = None):
+ """
+ Decorator that only runs the decorated function on the local main process.
+
+ Args:
+ function (`Callable`): The function to decorate.
+
+ Example:
+ ```python
+ # Assume we have 2 servers with 4 processes each.
+ from accelerate.state import PartialState
+
+ state = PartialState()
+
+
+ @state.on_local_main_process
+ def print_something():
+ print("This will be printed by process 0 only on each server.")
+
+
+ print_something()
+ # On server 1:
+ "This will be printed by process 0 only"
+ # On server 2:
+ "This will be printed by process 0 only"
+ ```
+ """
+ if self.is_local_main_process or not self.use_distributed:
+ return function
+ return do_nothing
+
+ def on_last_process(self, function: Callable[..., Any]):
+ """
+ Decorator that only runs the decorated function on the last process.
+
+ Args:
+ function (`Callable`): The function to decorate.
+
+ Example:
+ ```python
+ # Assume we have 4 processes.
+ from accelerate.state import PartialState
+
+ state = PartialState()
+
+
+ @state.on_last_process
+ def print_something():
+ print(f"Printed on process {state.process_index}")
+
+
+ print_something()
+ "Printed on process 3"
+ ```
+ """
+ if self.is_last_process or not self.use_distributed:
+ return function
+ return do_nothing
+
+ def on_process(self, function: Callable[..., Any] | None = None, process_index: int | None = None):
+ """
+ Decorator that only runs the decorated function on the process with the given index.
+
+ Args:
+ function (`Callable`, `optional`):
+ The function to decorate.
+ process_index (`int`, `optional`):
+ The index of the process on which to run the function.
+
+ Example:
+ ```python
+ # Assume we have 4 processes.
+ from accelerate.state import PartialState
+
+ state = PartialState()
+
+
+ @state.on_process(process_index=2)
+ def print_something():
+ print(f"Printed on process {state.process_index}")
+
+
+ print_something()
+ "Printed on process 2"
+ ```
+ """
+ if function is None:
+ return partial(self.on_process, process_index=process_index)
+ if (self.process_index == process_index) or (not self.use_distributed):
+ return function
+ return do_nothing
+
+ def on_local_process(self, function: Callable[..., Any] | None = None, local_process_index: int | None = None):
+ """
+ Decorator that only runs the decorated function on the process with the given index on the current node.
+
+ Args:
+ function (`Callable`, *optional*):
+ The function to decorate.
+ local_process_index (`int`, *optional*):
+ The index of the local process on which to run the function.
+
+ Example:
+ ```python
+ # Assume we have 2 servers with 4 processes each.
+ from accelerate import Accelerator
+
+ accelerator = Accelerator()
+
+
+ @accelerator.on_local_process(local_process_index=2)
+ def print_something():
+ print(f"Printed on process {accelerator.local_process_index}")
+
+
+ print_something()
+ # On server 1:
+ "Printed on process 2"
+ # On server 2:
+ "Printed on process 2"
+ ```
+ """
+ if function is None:
+ return partial(self.on_local_process, local_process_index=local_process_index)
+ if (self.local_process_index == local_process_index) or (not self.use_distributed):
+ return function
+ return do_nothing
+
+ def print(self, *args, **kwargs):
+ if self.is_local_main_process:
+ print(*args, **kwargs)
+
+ @property
+ def default_device(self) -> torch.device:
+ """
+ Returns the default device which is:
+ - MPS if `torch.backends.mps.is_available()` and `torch.backends.mps.is_built()` both return True.
+ - CUDA if `torch.cuda.is_available()`
+ - MLU if `is_mlu_available()`
+ - SDAA if `is_sdaa_available()`
+ - MUSA if `is_musa_available()`
+ - NPU if `is_npu_available()`
+ - HPU if `is_hpu_available()`
+ - CPU otherwise
+ """
+ if is_mps_available():
+ os.environ["PYTORCH_ENABLE_MPS_FALLBACK"] = "1"
+ return torch.device("mps")
+ elif is_mlu_available():
+ return torch.device("mlu")
+ elif is_sdaa_available():
+ return torch.device("sdaa")
+ elif is_musa_available():
+ return torch.device("musa")
+ # NPU should be checked before CUDA when using `transfer_to_npu`
+ # See issue #3020: https://github.com/huggingface/accelerate/issues/3020
+ elif is_npu_available():
+ return torch.device("npu")
+ elif is_hpu_available():
+ return torch.device("hpu")
+ elif torch.cuda.is_available():
+ return torch.device("cuda")
+ elif is_xpu_available():
+ return torch.device("xpu")
+ else:
+ return torch.device("cpu")
+
+ def _prepare_backend(
+ self, cpu: bool = False, sagemaker_dp=False, backend: str | None = None
+ ) -> tuple[str, DistributedType]:
+ "Prepares any imports needed before initializing the distributed backend and sets `self.backend` properly"
+ distributed_type = None
+ if sagemaker_dp:
+ import smdistributed.dataparallel.torch.torch_smddp # noqa
+
+ backend = "smddp"
+ distributed_type = DistributedType.MULTI_GPU
+ elif is_torch_xla_available():
+ backend = "xla"
+ distributed_type = DistributedType.XLA
+
+ elif int(os.environ.get("LOCAL_RANK", -1)) != -1 and not cpu:
+ if is_mlu_available():
+ backend = "cncl"
+ distributed_type = DistributedType.MULTI_MLU
+ if is_sdaa_available():
+ backend = "tccl"
+ distributed_type = DistributedType.MULTI_SDAA
+ elif is_musa_available():
+ backend = "mccl"
+ distributed_type = DistributedType.MULTI_MUSA
+ # NPU should be checked before CUDA when using `transfer_to_npu`
+ # See issue #3020: https://github.com/huggingface/accelerate/issues/3020
+ elif is_npu_available():
+ backend = "hccl"
+ distributed_type = DistributedType.MULTI_NPU
+ elif is_hpu_available(init_hccl=True):
+ if backend is None:
+ backend = "hccl"
+ distributed_type = DistributedType.MULTI_HPU
+ elif torch.cuda.is_available():
+ if backend is None:
+ backend = "nccl"
+ distributed_type = DistributedType.MULTI_GPU
+ elif is_xpu_available() and is_xccl_available():
+ if backend is None:
+ backend = "xccl"
+ distributed_type = DistributedType.MULTI_XPU
+
+ if distributed_type is None and (
+ int(os.environ.get("LOCAL_RANK", -1)) != -1
+ or get_int_from_env(["PMI_SIZE", "OMPI_COMM_WORLD_SIZE", "MV2_COMM_WORLD_SIZE", "WORLD_SIZE"], 1) > 1
+ ):
+ if not cpu and is_xpu_available():
+ distributed_type = DistributedType.MULTI_XPU
+ else:
+ distributed_type = DistributedType.MULTI_CPU
+
+ if (
+ backend in (None, "ccl")
+ and is_ccl_available()
+ and (get_int_from_env(["CCL_WORKER_COUNT"], 0) > 0 or distributed_type == DistributedType.MULTI_XPU)
+ ):
+ import oneccl_bindings_for_pytorch # noqa: F401
+
+ backend = "ccl"
+ elif backend in (None, "mpi") and torch.distributed.is_mpi_available():
+ backend = "mpi"
+ else:
+ backend = "gloo"
+ if distributed_type is None:
+ distributed_type = DistributedType.NO
+
+ return backend, distributed_type
+
+ def set_device(self):
+ """
+ Sets the device in `self.device` to the current distributed environment.
+ """
+ if self.device is not None:
+ return
+ if self.distributed_type == DistributedType.NO:
+ self.device = torch.device("cpu") if self._cpu else self.default_device
+ return
+ device = str(self.distributed_type).split(".")[-1].replace("MULTI_", "").lower()
+ if device not in ("cpu", "gpu", "mlu", "musa", "npu", "xpu", "xla", "hpu", "sdaa"):
+ raise ValueError(
+ f"Can't set device for {self.distributed_type} ({device}), verify we should be calling `_set_device()` for it!"
+ )
+ if device == "xla":
+ self.device = xm.xla_device()
+ elif device == "hpu":
+ self.device = torch.device("hpu", torch.hpu.current_device())
+ else:
+ if device == "gpu":
+ device = "cuda"
+ device_module = getattr(torch, device)
+ device_index = self.local_process_index % device_module.device_count()
+ self.device = torch.device(device, device_index)
+ device_module.set_device(self.device)
+
+ def destroy_process_group(self, group=None):
+ """
+ Destroys the process group. If one is not specified, the default process group is destroyed.
+ """
+ if self.fork_launched and group is None:
+ return
+ # needed when using torch.distributed.init_process_group
+ if torch.distributed.is_initialized():
+ torch.distributed.destroy_process_group(group)
+
+ def __getattr__(self, name: str):
+ # By this point we know that no attributes of `self` contain `name`,
+ # so we just modify the error message
+ if name in self._known_attrs:
+ raise AttributeError(
+ f"`PartialState` object has no attribute `{name}`. "
+ "This happens if `PartialState._reset_state()` was called and "
+ "an `Accelerator` or `PartialState` was not reinitialized."
+ )
+ # Raise a typical AttributeError
+ raise AttributeError(f"'PartialState' object has no attribute '{name}'")
+
+
+class AcceleratorState:
+ """
+ Singleton class that has information about the current training environment.
+
+ **Available attributes:**
+
+ - **device** (`torch.device`) -- The device to use.
+ - **distributed_type** ([`~accelerate.state.DistributedType`]) -- The type of distributed environment currently
+ in use.
+ - **parallelism_config** ([`~accelerate.utils.ParallelismConfig`]) -- The parallelism configuration for the
+ current training environment. This is used to configure the distributed training environment.
+ - **initialized** (`bool`) -- Whether or not the `AcceleratorState` has been initialized from `Accelerator`.
+ - **local_process_index** (`int`) -- The index of the current process on the current server.
+ - **mixed_precision** (`str`) -- Whether or not the current script will use mixed precision, and if so the type
+ of mixed precision being performed. (Choose from 'no','fp16','bf16 or 'fp8').
+ - **num_processes** (`int`) -- The number of processes currently launched in parallel.
+ - **process_index** (`int`) -- The index of the current process.
+ - **is_last_process** (`bool`) -- Whether or not the current process is the last one.
+ - **is_main_process** (`bool`) -- Whether or not the current process is the main one.
+ - **is_local_main_process** (`bool`) -- Whether or not the current process is the main one on the local node.
+ - **debug** (`bool`) -- Whether or not the current script is being run in debug mode.
+ """
+
+ _shared_state = SharedDict()
+ _known_attrs = PartialState._known_attrs + [
+ "deepspeed_plugin",
+ "use_ipex",
+ "fsdp_plugin",
+ "megatron_lm_plugin",
+ "dynamo_plugin",
+ ]
+
+ def __init__(
+ self,
+ mixed_precision: str | None = None,
+ cpu: bool = False,
+ dynamo_plugin=None,
+ deepspeed_plugin=None,
+ fsdp_plugin=None,
+ torch_tp_plugin=None,
+ megatron_lm_plugin=None,
+ parallelism_config=None,
+ _from_accelerator: bool = False,
+ **kwargs,
+ ):
+ self.__dict__ = self._shared_state
+ if parse_flag_from_env("ACCELERATE_USE_CPU"):
+ cpu = True
+ if PartialState._shared_state == {}:
+ PartialState(cpu, **kwargs)
+ self.__dict__.update(PartialState._shared_state)
+ self._check_initialized(mixed_precision, cpu)
+ if not self.initialized:
+ self.deepspeed_plugins = None
+ self.use_ipex = None
+ self.torch_tp_plugin = torch_tp_plugin
+ self.parallelism_config = parallelism_config
+ self.device_mesh = None
+ mixed_precision = (
+ parse_choice_from_env("ACCELERATE_MIXED_PRECISION", "no")
+ if mixed_precision is None
+ else mixed_precision.lower()
+ )
+ if mixed_precision == "fp8":
+ # this is confusing, why is is_fp8_available only checks for library availability ?
+ if not is_fp8_available():
+ raise ValueError(
+ "Using `fp8` precision requires `transformer_engine` or `MS-AMP` to be installed."
+ )
+ elif torch.cuda.is_available() and not check_cuda_fp8_capability():
+ logger.warning(
+ f"The current device has compute capability of {torch.cuda.get_device_capability()} which is "
+ "insufficient for FP8 mixed precision training (requires a GPU Hopper/Ada Lovelace "
+ "or higher, compute capability of 8.9 or higher). Will use FP16 instead."
+ )
+ mixed_precision = "fp16"
+ elif is_habana_gaudi1():
+ logger.warning(
+ "The current HPU device is Gaudi1 which does not support FP8 mixed precision training (requires "
+ "Gaudi2 or higher). Will use BF16 instead."
+ )
+ mixed_precision = "bf16"
+
+ self.dynamo_plugin = dynamo_plugin
+ if not _from_accelerator:
+ raise ValueError(
+ "Please make sure to properly initialize your accelerator via `accelerator = Accelerator()` "
+ "before using any functionality from the `accelerate` library."
+ )
+ # deepspeed handles mixed_precision using deepspeed_config. But we need to set it to fp8
+ # if we're using fp8.
+ if self.distributed_type == DistributedType.DEEPSPEED and mixed_precision != "fp8":
+ self._mixed_precision = "no"
+ else:
+ self._mixed_precision = mixed_precision
+
+ if self.distributed_type == DistributedType.XLA and is_torch_xla_available(check_is_tpu=True):
+ if mixed_precision == "bf16":
+ if os.environ.get("ACCELERATE_DOWNCAST_BF16"):
+ os.environ["XLA_USE_BF16"] = str(0)
+ os.environ["XLA_DOWNCAST_BF16"] = str(1)
+ self.downcast_bfloat = True
+ else:
+ os.environ["XLA_USE_BF16"] = str(1)
+ os.environ["XLA_DOWNCAST_BF16"] = str(0)
+ self.downcast_bfloat = False
+ elif os.environ.get("ACCELERATE_USE_DEEPSPEED", "false").lower() == "true" and not cpu:
+ self.distributed_type = DistributedType.DEEPSPEED
+ if not isinstance(deepspeed_plugin, dict):
+ deepspeed_plugin.set_mixed_precision(mixed_precision)
+ deepspeed_plugin.select(_from_accelerator_state=True)
+ else:
+ for plugin in deepspeed_plugin.values():
+ plugin.set_mixed_precision(mixed_precision)
+ # The first plugin passed in is always the active one
+ first_plugin = next(iter(deepspeed_plugin.values()))
+ first_plugin.select(_from_accelerator_state=True)
+ self.deepspeed_plugins = deepspeed_plugin
+ elif self.distributed_type in [
+ DistributedType.MULTI_GPU,
+ DistributedType.MULTI_MLU,
+ DistributedType.MULTI_SDAA,
+ DistributedType.MULTI_MUSA,
+ DistributedType.MULTI_NPU,
+ DistributedType.MULTI_XPU,
+ DistributedType.MULTI_HPU,
+ ]:
+ # TODO: Siro - remove when axolotl fixes their side
+ if not os.environ.get("ACCELERATE_ALLOW_CP_STANDALONE", "false").lower() == "true":
+ if self.parallelism_config and self.parallelism_config.cp_enabled and fsdp_plugin is None:
+ raise ValueError(
+ "`cp_size > 1` specified in the `parallelism_config`, but no `fsdp_plugin` was provided. We need a `fsdp_plugin` to use context parallelism with `cp_backend=torch`, as we also shard the model across the device mesh to save more memory"
+ )
+ if (
+ self.parallelism_config is not None
+ and self.parallelism_config.cp_enabled
+ and fsdp_plugin.fsdp_version == 1
+ ):
+ raise ValueError(
+ "Using `cp_size>1` requires FSDP2, but the provided `fsdp_plugin` is using FSDP1. "
+ )
+ if (os.environ.get("ACCELERATE_USE_FSDP", "false").lower() == "true" or fsdp_plugin is not None) or (
+ self.parallelism_config is not None and self.parallelism_config.cp_enabled
+ ):
+ self.distributed_type = DistributedType.FSDP
+ if self._mixed_precision != "no" and fsdp_plugin is not None:
+ fsdp_plugin.set_mixed_precision(self._mixed_precision)
+ self.fsdp_plugin = fsdp_plugin
+ if os.environ.get(
+ "ACCELERATE_USE_MEGATRON_LM", "false"
+ ).lower() == "true" and self.distributed_type not in [
+ DistributedType.MULTI_XPU,
+ ]:
+ self.distributed_type = DistributedType.MEGATRON_LM
+ megatron_lm_plugin.set_mixed_precision(self._mixed_precision)
+ self.megatron_lm_plugin = megatron_lm_plugin
+ elif self.distributed_type in [DistributedType.MULTI_CPU, DistributedType.MULTI_XPU, DistributedType.NO]:
+ if is_ipex_available():
+ # check if user disables it explicitly
+ self.use_ipex = parse_flag_from_env("ACCELERATE_USE_IPEX", default=True)
+ else:
+ self.use_ipex = False
+ if (
+ self.dynamo_plugin.backend != DynamoBackend.NO
+ and self._mixed_precision == "no"
+ and self.device.type == "cuda"
+ ):
+ torch.backends.cuda.matmul.allow_tf32 = True
+ if (
+ self.dynamo_plugin.backend != DynamoBackend.NO
+ and self._mixed_precision == "no"
+ and self.device.type == "musa"
+ ):
+ torch.backends.musa.matmul.allow_tf32 = True
+ PartialState._shared_state["distributed_type"] = self.distributed_type
+
+ @property
+ def initialized(self) -> bool:
+ return self._shared_state != PartialState._shared_state
+
+ def __repr__(self):
+ repr = PartialState().__repr__() + f"\nMixed precision type: {self.mixed_precision}\n"
+ if self.distributed_type == DistributedType.DEEPSPEED:
+ repr += f"ds_config: {self.deepspeed_plugin.deepspeed_config}\n"
+ return repr
+
+ def _check_initialized(self, mixed_precision=None, cpu=None):
+ "Checks if a modification is trying to be made and the `AcceleratorState` has already been initialized"
+ if self.initialized:
+ err = "AcceleratorState has already been initialized and cannot be changed, restart your runtime completely and pass `{flag}` to `Accelerator()`."
+ if cpu and self.device.type != "cpu":
+ raise ValueError(err.format(flag="cpu=True"))
+ if (
+ mixed_precision is not None
+ and mixed_precision != self._mixed_precision
+ and self.distributed_type != DistributedType.DEEPSPEED
+ ):
+ raise ValueError(err.format(flag=f"mixed_precision='{mixed_precision}'"))
+
+ @property
+ def mixed_precision(self):
+ if self.distributed_type == DistributedType.DEEPSPEED and self._mixed_precision != "fp8":
+ config = self.deepspeed_plugin.deepspeed_config
+ if config.get("fp16", {}).get("enabled", False):
+ mixed_precision = "fp16"
+ elif config.get("bf16", {}).get("enabled", False):
+ mixed_precision = "bf16"
+ else:
+ mixed_precision = "no"
+ else:
+ mixed_precision = self._mixed_precision
+ return mixed_precision
+
+ @staticmethod
+ def _reset_state(reset_partial_state: bool = False):
+ "Resets `_shared_state`, is used internally and should not be called"
+ AcceleratorState._shared_state.clear()
+ if reset_partial_state:
+ PartialState._reset_state()
+
+ def destroy_process_group(self, group=None):
+ """
+ Destroys the process group. If one is not specified, the default process group is destroyed.
+
+ If `self.fork_launched` is `True` and `group` is `None`, nothing happens.
+ """
+ PartialState().destroy_process_group(group)
+
+ @property
+ def fork_launched(self):
+ return PartialState().fork_launched
+
+ @property
+ def use_distributed(self):
+ """
+ Whether the Accelerator is configured for distributed training
+ """
+ return PartialState().use_distributed
+
+ @property
+ def is_fsdp2(self) -> bool:
+ return self.distributed_type == DistributedType.FSDP and self.fsdp_plugin.fsdp_version == 2
+
+ @property
+ def is_last_process(self) -> bool:
+ "Returns whether the current process is the last one"
+ return PartialState().is_last_process
+
+ @property
+ def is_main_process(self) -> bool:
+ "Returns whether the current process is the main process"
+ return PartialState().is_main_process
+
+ @property
+ def is_local_main_process(self) -> bool:
+ "Returns whether the current process is the main process on the local node"
+ return PartialState().is_local_main_process
+
+ def wait_for_everyone(self):
+ PartialState().wait_for_everyone()
+
+ @contextmanager
+ def split_between_processes(self, inputs: list | tuple | dict | torch.Tensor, apply_padding: bool = False):
+ """
+ Splits `input` between `self.num_processes` quickly and can be then used on that process. Useful when doing
+ distributed inference, such as with different prompts.
+
+ Note that when using a `dict`, all keys need to have the same number of elements.
+
+ Args:
+ inputs (`list`, `tuple`, `torch.Tensor`, or `dict` of `list`/`tuple`/`torch.Tensor`):
+ The input to split between processes.
+ apply_padding (`bool`, `optional`, defaults to `False`):
+ Whether to apply padding by repeating the last element of the input so that all processes have the same
+ number of elements. Useful when trying to perform actions such as `gather()` on the outputs or passing
+ in less inputs than there are processes. If so, just remember to drop the padded elements afterwards.
+
+
+ Example:
+
+ ```python
+ # Assume there are two processes
+ from accelerate.state import AcceleratorState
+
+ state = AcceleratorState()
+ with state.split_between_processes(["A", "B", "C"]) as inputs:
+ print(inputs)
+ # Process 0
+ ["A", "B"]
+ # Process 1
+ ["C"]
+
+ with state.split_between_processes(["A", "B", "C"], apply_padding=True) as inputs:
+ print(inputs)
+ # Process 0
+ ["A", "B"]
+ # Process 1
+ ["C", "C"]
+ ```
+ """
+ with PartialState().split_between_processes(inputs, apply_padding=apply_padding) as inputs:
+ yield inputs
+
+ @contextmanager
+ def main_process_first(self):
+ """
+ Lets the main process go first inside a with block.
+
+ The other processes will enter the with block after the main process exits.
+ """
+ with PartialState().main_process_first():
+ yield
+
+ @contextmanager
+ def local_main_process_first(self):
+ """
+ Lets the local main process go inside a with block.
+
+ The other processes will enter the with block after the main process exits.
+ """
+ with PartialState().local_main_process_first():
+ yield
+
+ @property
+ def deepspeed_plugin(self):
+ """
+ Returns the currently active DeepSpeedPlugin.
+
+ If not using deepspeed, returns `None`.
+ """
+ # To maintain original behavior, return None if not using deepspeed.
+ if self.distributed_type != DistributedType.DEEPSPEED:
+ return None
+ from accelerate.utils.deepspeed import get_active_deepspeed_plugin
+
+ return get_active_deepspeed_plugin(self)
+
+ @deepspeed_required
+ def get_deepspeed_plugin(self, name: str):
+ """
+ Returns the DeepSpeedPlugin with the given plugin_key.
+ """
+ return self.deepspeed_plugins[name]
+
+ @deepspeed_required
+ def select_deepspeed_plugin(self, name: str | None = None):
+ """
+ Activates the DeepSpeedPlugin with the given `name`, and will disable all other plugins.
+ """
+ for key, plugin in self.deepspeed_plugins.items():
+ if key != name:
+ plugin._unselect()
+ self.deepspeed_plugins[name].select(_from_accelerator_state=True)
+
+ def print(self, *args, **kwargs):
+ PartialState().print(*args, **kwargs)
+
+ def __getattr__(self, name: str):
+ # By this point we know that no attributes of `self` contain `name`,
+ # so we just modify the error message
+ if name in self._known_attrs:
+ raise AttributeError(
+ f"`AcceleratorState` object has no attribute `{name}`. "
+ "This happens if `AcceleratorState._reset_state()` was called and "
+ "an `Accelerator` or `PartialState` was not reinitialized."
+ )
+ # Raise a typical AttributeError
+ raise AttributeError(f"'AcceleratorState' object has no attribute '{name}'")
+
+
+class GradientState:
+ """
+ Singleton class that has information related to gradient synchronization for gradient accumulation
+
+ **Available attributes:**
+
+ - **end_of_dataloader** (`bool`) -- Whether we have reached the end the current dataloader
+ - **remainder** (`int`) -- The number of extra samples that were added from padding the dataloader
+ - **sync_gradients** (`bool`) -- Whether the gradients should be synced across all devices
+ - **active_dataloader** (`Optional[DataLoader]`) -- The dataloader that is currently being iterated over
+ - **dataloader_references** (`List[Optional[DataLoader]]`) -- A list of references to the dataloaders that are
+ being iterated over
+ - **num_steps** (`int`) -- The number of steps to accumulate over
+ - **adjust_scheduler** (`bool`) -- Whether the scheduler should be adjusted to account for the gradient
+ accumulation
+ - **sync_with_dataloader** (`bool`) -- Whether the gradients should be synced at the end of the dataloader
+ iteration and the number of total steps reset
+ - **is_xla_gradients_synced** (`bool`) -- Whether the XLA gradients have been synchronized. It is initialized
+ as false. Once gradients have been reduced before the optimizer step, this flag is set to true. Subsequently,
+ after each step, the flag is reset to false. FSDP will always synchronize the gradients, hence
+ is_xla_gradients_synced is always true.
+ """
+
+ _shared_state = SharedDict()
+
+ def __init__(self, gradient_accumulation_plugin: GradientAccumulationPlugin | None = None):
+ self.__dict__ = self._shared_state
+ if not self.initialized:
+ self.sync_gradients = True
+ self._dataloader_references_ref = [None]
+ self.plugin_kwargs = (
+ gradient_accumulation_plugin.to_kwargs() if gradient_accumulation_plugin is not None else {}
+ )
+ self._is_xla_gradients_synced = False
+
+ # Plugin args are different and can be updated
+ if gradient_accumulation_plugin is not None and self.plugin_kwargs != gradient_accumulation_plugin.to_kwargs():
+ self.plugin_kwargs = gradient_accumulation_plugin.to_kwargs()
+
+ @property
+ def num_steps(self) -> int:
+ "Returns the number of steps to accumulate over"
+ return self.plugin_kwargs.get("num_steps", 1)
+
+ @property
+ def adjust_scheduler(self) -> bool:
+ "Returns whether the scheduler should be adjusted"
+ return self.plugin_kwargs.get("adjust_scheduler", False)
+
+ @property
+ def sync_with_dataloader(self) -> bool:
+ "Returns whether the gradients should be synced at the end of the dataloader iteration and the number of total steps reset"
+ return self.plugin_kwargs.get("sync_with_dataloader", True)
+
+ @property
+ def initialized(self) -> bool:
+ "Returns whether the `GradientState` has been initialized"
+ return GradientState._shared_state != {}
+
+ @property
+ def end_of_dataloader(self) -> bool:
+ "Returns whether we have reached the end of the current dataloader"
+ if not self.in_dataloader:
+ return False
+ return self.active_dataloader.end_of_dataloader
+
+ @property
+ def remainder(self) -> int:
+ "Returns the number of extra samples that were added from padding the dataloader"
+ if not self.in_dataloader:
+ return -1
+ return self.active_dataloader.remainder
+
+ def __repr__(self):
+ return (
+ f"Sync Gradients: {self.sync_gradients}\n"
+ f"At end of current dataloader: {self.end_of_dataloader}\n"
+ f"Extra samples added: {self.remainder}\n"
+ f"Gradient accumulation plugin: {self.plugin_kwargs}\n"
+ )
+
+ @property
+ def is_xla_gradients_synced(self):
+ "Returns the value of is_xla_gradients_synced. FSDP will always synchronize the gradients, hence is_xla_gradients_synced is always true."
+ if parse_flag_from_env("ACCELERATE_USE_FSDP", default=False):
+ return True
+ return self._is_xla_gradients_synced
+
+ @is_xla_gradients_synced.setter
+ def is_xla_gradients_synced(self, is_synced):
+ "Set the _is_xla_gradients_synced attribute."
+ self._is_xla_gradients_synced = is_synced
+
+ def _set_sync_gradients(self, sync_gradients):
+ "Private function that sets whether gradients should be synchronized. Users should not have to call this."
+ self.sync_gradients = sync_gradients
+ # Allow grad-sync to automatically work on TPUs
+ if (
+ self.sync_gradients
+ and is_torch_xla_available(check_is_tpu=True)
+ and PartialState().distributed_type == DistributedType.XLA
+ ):
+ xm.mark_step()
+
+ def _add_dataloader(self, dataloader):
+ "Private function that adds a dataloader to `self.dataloader_references` and sets `in_dataloader` to `True`. Users should not have to call this."
+ # We explicitly use assignment to ensure that the property setter is triggered, which is required for garbage collection.
+ # Avoid using self.dataloader_references.append as it will not trigger the setter.
+ self.dataloader_references += [dataloader]
+
+ def _remove_dataloader(self, dataloader):
+ "Private function that removes a dataloader from `self.dataloader_references` and sets `in_dataloader` to `False` if there are no more dataloaders. Users should not have to call this."
+ # We explicitly use assignment to ensure that the property setter is triggered.
+ self.dataloader_references = [
+ dataloader_ref for dataloader_ref in self.dataloader_references if dataloader_ref != dataloader
+ ]
+
+ @property
+ def active_dataloader(self):
+ return self.dataloader_references[-1]
+
+ @property
+ def dataloader_references(self):
+ # We use a property getter and setter with weakrefs to avoid circular references that prevent garbage collection
+ return [reference() if reference is not None else reference for reference in self._dataloader_references_ref]
+
+ @dataloader_references.setter
+ def dataloader_references(self, references):
+ self._dataloader_references_ref = [
+ weakref.ref(dataloader) if dataloader is not None else dataloader for dataloader in references
+ ]
+
+ @property
+ def in_dataloader(self) -> bool:
+ "Returns whether the current process is in a dataloader"
+ return self.active_dataloader is not None
+
+ @staticmethod
+ def _reset_state():
+ "Resets `_shared_state`, is used internally and should not be called"
+ GradientState._shared_state.clear()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/__init__.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..67031886219f56344b1173c792ac4d8d421746d3
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/__init__.py
@@ -0,0 +1,66 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from .testing import (
+ DEFAULT_LAUNCH_COMMAND,
+ are_the_same_tensors,
+ assert_exception,
+ capture_call_output,
+ device_count,
+ execute_subprocess_async,
+ get_launch_command,
+ get_torch_dist_unique_port,
+ memory_allocated_func,
+ path_in_accelerate_package,
+ pytest_xdist_worker_id,
+ require_bnb,
+ require_cpu,
+ require_cuda,
+ require_cuda_or_hpu,
+ require_cuda_or_xpu,
+ require_fp8,
+ require_fp16,
+ require_huggingface_suite,
+ require_mlu,
+ require_mps,
+ require_multi_device,
+ require_multi_gpu,
+ require_multi_gpu_or_xpu,
+ require_multi_xpu,
+ require_musa,
+ require_non_cpu,
+ require_non_hpu,
+ require_non_torch_xla,
+ require_non_xpu,
+ require_npu,
+ require_pippy,
+ require_sdaa,
+ require_single_device,
+ require_single_gpu,
+ require_single_xpu,
+ require_torch_min_version,
+ require_torchao,
+ require_torchvision,
+ require_tpu,
+ require_transformer_engine,
+ require_transformer_engine_mxfp8,
+ require_xpu,
+ run_first,
+ skip,
+ slow,
+ torch_device,
+)
+from .training import RegressionDataset, RegressionModel
+
+
+from .scripts import test_script, test_sync, test_ops # isort: skip
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/examples.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/examples.py
new file mode 100644
index 0000000000000000000000000000000000000000..18549cdb31492650e707b6008e25eeac8e33b04e
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/examples.py
@@ -0,0 +1,148 @@
+#!/usr/bin/env python
+
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+A collection of utilities for comparing `examples/complete_*_example.py` scripts with the capabilities inside of each
+`examples/by_feature` example. `compare_against_test` is the main function that should be used when testing, while the
+others are used to either get the code that matters, or to preprocess them (such as stripping comments)
+"""
+
+import os
+from typing import Optional
+
+
+def get_function_contents_by_name(lines: list[str], name: str):
+ """
+ Extracts a function from `lines` of segmented source code with the name `name`.
+
+ Args:
+ lines (`List[str]`):
+ Source code of a script separated by line.
+ name (`str`):
+ The name of the function to extract. Should be either `training_function` or `main`
+ """
+ if name != "training_function" and name != "main":
+ raise ValueError(f"Incorrect function name passed: {name}, choose either 'main' or 'training_function'")
+ good_lines, found_start = [], False
+ for line in lines:
+ if not found_start and f"def {name}" in line:
+ found_start = True
+ good_lines.append(line)
+ continue
+ if found_start:
+ if name == "training_function" and "def main" in line:
+ return good_lines
+ if name == "main" and "if __name__" in line:
+ return good_lines
+ good_lines.append(line)
+
+
+def clean_lines(lines: list[str]):
+ """
+ Filters `lines` and removes any entries that start with a comment ('#') or is just a newline ('\n')
+
+ Args:
+ lines (`List[str]`):
+ Source code of a script separated by line.
+ """
+ return [line for line in lines if not line.lstrip().startswith("#") and line != "\n"]
+
+
+def compare_against_test(
+ base_filename: str, feature_filename: str, parser_only: bool, secondary_filename: Optional[str] = None
+):
+ """
+ Tests whether the additional code inside of `feature_filename` was implemented in `base_filename`. This should be
+ used when testing to see if `complete_*_.py` examples have all of the implementations from each of the
+ `examples/by_feature/*` scripts.
+
+ It utilizes `nlp_example.py` to extract out all of the repeated training code, so that only the new additional code
+ is examined and checked. If something *other* than `nlp_example.py` should be used, such as `cv_example.py` for the
+ `complete_cv_example.py` script, it should be passed in for the `secondary_filename` parameter.
+
+ Args:
+ base_filename (`str` or `os.PathLike`):
+ The filepath of a single "complete" example script to test, such as `examples/complete_cv_example.py`
+ feature_filename (`str` or `os.PathLike`):
+ The filepath of a single feature example script. The contents of this script are checked to see if they
+ exist in `base_filename`
+ parser_only (`bool`):
+ Whether to compare only the `main()` sections in both files, or to compare the contents of
+ `training_loop()`
+ secondary_filename (`str`, *optional*):
+ A potential secondary filepath that should be included in the check. This function extracts the base
+ functionalities off of "examples/nlp_example.py", so if `base_filename` is a script other than
+ `complete_nlp_example.py`, the template script should be included here. Such as `examples/cv_example.py`
+ """
+ with open(base_filename) as f:
+ base_file_contents = f.readlines()
+ with open(os.path.abspath(os.path.join("examples", "nlp_example.py"))) as f:
+ full_file_contents = f.readlines()
+ with open(feature_filename) as f:
+ feature_file_contents = f.readlines()
+ if secondary_filename is not None:
+ with open(secondary_filename) as f:
+ secondary_file_contents = f.readlines()
+
+ # This is our base, we remove all the code from here in our `full_filename` and `feature_filename` to find the new content
+ if parser_only:
+ base_file_func = clean_lines(get_function_contents_by_name(base_file_contents, "main"))
+ full_file_func = clean_lines(get_function_contents_by_name(full_file_contents, "main"))
+ feature_file_func = clean_lines(get_function_contents_by_name(feature_file_contents, "main"))
+ if secondary_filename is not None:
+ secondary_file_func = clean_lines(get_function_contents_by_name(secondary_file_contents, "main"))
+ else:
+ base_file_func = clean_lines(get_function_contents_by_name(base_file_contents, "training_function"))
+ full_file_func = clean_lines(get_function_contents_by_name(full_file_contents, "training_function"))
+ feature_file_func = clean_lines(get_function_contents_by_name(feature_file_contents, "training_function"))
+ if secondary_filename is not None:
+ secondary_file_func = clean_lines(
+ get_function_contents_by_name(secondary_file_contents, "training_function")
+ )
+
+ _dl_line = "train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size)\n"
+
+ # Specific code in our script that differs from the full version, aka what is new
+ new_feature_code = []
+ passed_idxs = [] # We keep track of the idxs just in case it's a repeated statement
+ it = iter(feature_file_func)
+ for i in range(len(feature_file_func) - 1):
+ if i not in passed_idxs:
+ line = next(it)
+ if (line not in full_file_func) and (line.lstrip() != _dl_line):
+ if "TESTING_MOCKED_DATALOADERS" not in line:
+ new_feature_code.append(line)
+ passed_idxs.append(i)
+ else:
+ # Skip over the `config['num_epochs'] = 2` statement
+ _ = next(it)
+
+ # Extract out just the new parts from the full_file_training_func
+ new_full_example_parts = []
+ passed_idxs = [] # We keep track of the idxs just in case it's a repeated statement
+ for i, line in enumerate(base_file_func):
+ if i not in passed_idxs:
+ if (line not in full_file_func) and (line.lstrip() != _dl_line):
+ if "TESTING_MOCKED_DATALOADERS" not in line:
+ new_full_example_parts.append(line)
+ passed_idxs.append(i)
+
+ # Finally, get the overall diff
+ diff_from_example = [line for line in new_feature_code if line not in new_full_example_parts]
+ if secondary_filename is not None:
+ diff_from_two = [line for line in full_file_contents if line not in secondary_file_func]
+ diff_from_example = [line for line in diff_from_example if line not in diff_from_two]
+
+ return diff_from_example
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/__init__.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..c9cbe26c257b515f657c05e1996d517e69613972
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/__init__.py
@@ -0,0 +1,13 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/__init__.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..c9cbe26c257b515f657c05e1996d517e69613972
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/__init__.py
@@ -0,0 +1,13 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_checkpointing.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_checkpointing.py
new file mode 100644
index 0000000000000000000000000000000000000000..6a1553898ec3d55e64822c204ddf7e705069ce8a
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_checkpointing.py
@@ -0,0 +1,269 @@
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import json
+import os
+
+import evaluate
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup, set_seed
+
+from accelerate import Accelerator, DistributedType
+from accelerate.utils.deepspeed import DummyOptim, DummyScheduler
+
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+
+def get_dataloaders(accelerator: Accelerator, batch_size: int = 16, model_name: str = "bert-base-cased"):
+ """
+ Creates a set of `DataLoader`s for the `glue` dataset.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ model_name (`str`, *optional*):
+ """
+ tokenizer = AutoTokenizer.from_pretrained(model_name)
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ tokenized_datasets = datasets.map(
+ tokenize_function, batched=True, remove_columns=["idx", "sentence1", "sentence2"], load_from_cache_file=False
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ if accelerator.distributed_type == DistributedType.XLA:
+ return tokenizer.pad(examples, padding="max_length", max_length=128, return_tensors="pt")
+ return tokenizer.pad(examples, padding="longest", return_tensors="pt")
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+def evaluation_loop(accelerator, model, eval_dataloader, metric):
+ model.eval()
+ samples_seen = 0
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ # It is slightly faster to call this once, than multiple times
+ predictions, references = accelerator.gather(
+ (predictions, batch["labels"])
+ ) # If we are in a multiprocess environment, the last batch has duplicates
+ if accelerator.use_distributed:
+ if step == len(eval_dataloader) - 1:
+ predictions = predictions[: len(eval_dataloader.dataset) - samples_seen]
+ references = references[: len(eval_dataloader.dataset) - samples_seen]
+ else:
+ samples_seen += references.shape[0]
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ return eval_metric["accuracy"]
+
+
+def training_function(config, args):
+ # Initialize accelerator
+ accelerator = Accelerator()
+
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+ model_name = args.model_name_or_path
+
+ set_seed(seed)
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size, model_name)
+
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained(model_name, return_dict=True)
+
+ # Instantiate optimizer
+ optimizer_cls = (
+ AdamW
+ if accelerator.state.deepspeed_plugin is None
+ or "optimizer" not in accelerator.state.deepspeed_plugin.deepspeed_config
+ else DummyOptim
+ )
+ optimizer = optimizer_cls(params=model.parameters(), lr=lr)
+
+ if accelerator.state.deepspeed_plugin is not None:
+ gradient_accumulation_steps = accelerator.state.deepspeed_plugin.deepspeed_config[
+ "gradient_accumulation_steps"
+ ]
+ else:
+ gradient_accumulation_steps = 1
+ max_training_steps = (len(train_dataloader) * num_epochs) // gradient_accumulation_steps
+
+ # Instantiate scheduler
+ if (
+ accelerator.state.deepspeed_plugin is None
+ or "scheduler" not in accelerator.state.deepspeed_plugin.deepspeed_config
+ ):
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=0,
+ num_training_steps=max_training_steps,
+ )
+ else:
+ lr_scheduler = DummyScheduler(optimizer, total_num_steps=max_training_steps, warmup_num_steps=0)
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # We need to keep track of how many total steps we have iterated over
+ overall_step = 0
+ # We also need to keep track of the stating epoch so files are named properly
+ starting_epoch = 0
+ metric = evaluate.load("glue", "mrpc")
+ ending_epoch = num_epochs
+
+ if args.partial_train_epoch is not None:
+ ending_epoch = args.partial_train_epoch
+
+ if args.resume_from_checkpoint:
+ accelerator.load_state(args.resume_from_checkpoint)
+ epoch_string = args.resume_from_checkpoint.split("epoch_")[1]
+ state_epoch_num = ""
+ for char in epoch_string:
+ if char.isdigit():
+ state_epoch_num += char
+ else:
+ break
+ starting_epoch = int(state_epoch_num) + 1
+ accuracy = evaluation_loop(accelerator, model, eval_dataloader, metric)
+ accelerator.print("resumed checkpoint performance:", accuracy)
+ accelerator.print("resumed checkpoint's scheduler's lr:", lr_scheduler.get_lr()[0])
+ accelerator.print("resumed optimizers's lr:", optimizer.param_groups[0]["lr"])
+ with open(os.path.join(args.output_dir, f"state_{starting_epoch - 1}.json")) as f:
+ resumed_state = json.load(f)
+ assert resumed_state["accuracy"] == accuracy, "Accuracy mismatch, loading from checkpoint failed"
+ assert resumed_state["lr"] == lr_scheduler.get_lr()[0], (
+ "Scheduler learning rate mismatch, loading from checkpoint failed"
+ )
+ assert resumed_state["optimizer_lr"] == optimizer.param_groups[0]["lr"], (
+ "Optimizer learning rate mismatch, loading from checkpoint failed"
+ )
+ assert resumed_state["epoch"] == starting_epoch - 1, "Epoch mismatch, loading from checkpoint failed"
+ return
+
+ # Now we train the model
+ state = {}
+ for epoch in range(starting_epoch, ending_epoch):
+ model.train()
+ for step, batch in enumerate(train_dataloader):
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss = loss / gradient_accumulation_steps
+ accelerator.backward(loss)
+ if step % gradient_accumulation_steps == 0:
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ overall_step += 1
+ output_dir = f"epoch_{epoch}"
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+ accuracy = evaluation_loop(accelerator, model, eval_dataloader, metric)
+ state["accuracy"] = accuracy
+ state["lr"] = lr_scheduler.get_lr()[0]
+ state["optimizer_lr"] = optimizer.param_groups[0]["lr"]
+ state["epoch"] = epoch
+ state["step"] = overall_step
+ accelerator.print(f"epoch {epoch}:", state)
+
+ accelerator.wait_for_everyone()
+ if accelerator.is_main_process:
+ with open(os.path.join(args.output_dir, f"state_{epoch}.json"), "w") as f:
+ json.dump(state, f)
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script tracking peak GPU memory usage.")
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ default="bert-base-cased",
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=False,
+ )
+ parser.add_argument(
+ "--output_dir",
+ type=str,
+ default=".",
+ help="Optional save directory where all checkpoint folders will be stored. Default is the current working directory.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--partial_train_epoch",
+ type=int,
+ default=None,
+ help="If passed, the training will stop after this number of epochs.",
+ )
+ parser.add_argument(
+ "--num_epochs",
+ type=int,
+ default=2,
+ help="Number of train epochs.",
+ )
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": args.num_epochs, "seed": 42, "batch_size": 16}
+
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_ds_alst_ulysses_sp.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_ds_alst_ulysses_sp.py
new file mode 100644
index 0000000000000000000000000000000000000000..eb910a45dfbe9924ab0b417bfafc5d6a89567edd
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_ds_alst_ulysses_sp.py
@@ -0,0 +1,129 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+Test script for verifying ALST/Ulysses SP works
+"""
+
+import torch
+from deepspeed.runtime.utils import move_to_device
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+from accelerate import Accelerator
+from accelerate.utils import ParallelismConfig, set_seed
+from accelerate.utils.dataclasses import DeepSpeedSequenceParallelConfig
+
+
+set_seed(42)
+
+world_size = 2
+model_name = "hf-internal-testing/tiny-random-LlamaForCausalLM"
+
+micro_batch_size = 1
+
+parallelism_config = ParallelismConfig(
+ sp_backend="deepspeed",
+ sp_size=world_size,
+ # dp_shard_size=1, # set if dp is wanted as well
+ sp_handler=DeepSpeedSequenceParallelConfig(
+ sp_seq_length=256,
+ sp_seq_length_is_variable=True,
+ sp_attn_implementation="sdpa",
+ ),
+)
+
+accelerator = Accelerator(
+ parallelism_config=parallelism_config,
+)
+
+tokenizer = AutoTokenizer.from_pretrained(model_name)
+model = AutoModelForCausalLM.from_pretrained(model_name)
+
+samples = 4
+seqlen = 32
+input_ids = torch.arange(1, seqlen * samples + 1).view(-1, seqlen) + 100
+position_ids = torch.arange(seqlen * samples).view(-1, seqlen)
+
+ds = torch.utils.data.TensorDataset(input_ids, position_ids)
+
+
+def collate_fn(batch):
+ input_ids, position_ids = batch[0]
+ return dict(
+ input_ids=input_ids.unsqueeze(0),
+ position_ids=position_ids.unsqueeze(0),
+ labels=input_ids.unsqueeze(0),
+ )
+
+
+dl = torch.utils.data.DataLoader(ds, batch_size=micro_batch_size, collate_fn=collate_fn)
+
+optimizer = torch.optim.Adam(model.parameters(), lr=1e-5)
+
+rank = torch.distributed.get_rank()
+
+if rank == 0:
+ print(f"DL orig: {len(dl)} samples")
+
+model, optimizer, dl = accelerator.prepare(model, optimizer, dl)
+
+if rank == 0:
+ print(f"DL w/ adapter: {len(dl)} samples")
+
+sp_size = parallelism_config.sp_size if parallelism_config else 1
+if sp_size > 1:
+ sp_group = accelerator.torch_device_mesh["sp"].get_group()
+ sp_world_size = parallelism_config.sp_size
+
+unwrapped_model = accelerator.unwrap_model(model)
+
+# Normal training loop
+for iter, batch in enumerate(dl):
+ optimizer.zero_grad()
+
+ if rank == 0:
+ print(f"batch {iter}: seqlen: {len(batch['input_ids'][0])}")
+ batch = move_to_device(batch, model.device)
+ outputs = model(**batch)
+
+ shift_labels = batch["shift_labels"]
+ loss = unwrapped_model.loss_function(
+ logits=outputs.logits,
+ labels=None,
+ shift_labels=shift_labels,
+ vocab_size=unwrapped_model.config.vocab_size,
+ )
+
+ if sp_size > 1:
+ # differentiable weighted per-shard-loss aggregation across ranks
+ losses_per_rank = torch.distributed.nn.functional.all_gather(loss, group=sp_group)
+ # special dealing with SFT that has prompt tokens that aren't used in loss computation
+ good_tokens = (shift_labels != -100).view(-1).sum()
+ good_tokens_per_rank = torch.distributed.nn.functional.all_gather(good_tokens, group=sp_group)
+ total_loss = sum(
+ losses_per_rank[rank] * good_tokens_per_rank[rank]
+ for rank in range(sp_world_size)
+ if good_tokens_per_rank[rank] > 0
+ )
+ total_good_tokens = sum(good_tokens_per_rank)
+ loss = total_loss / max(total_good_tokens, 1)
+
+ if rank == 0:
+ accelerator.print(f"{iter}: {loss=}")
+ accelerator.log(dict(train_loss=loss, step=iter))
+
+ accelerator.backward(loss)
+ optimizer.step()
+
+accelerator.end_training()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_ds_multiple_model.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_ds_multiple_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..a9ff3f3d2d0214f2b36f2b51e1d029b6ddf7cb7c
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_ds_multiple_model.py
@@ -0,0 +1,331 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+Test script for verifying multiple models can be utilized with Accelerate + DeepSpeed:
+
+Scenario 1: One model is training, another model is being used for inference/logits to impact training in some form.
+Scenario 2: Two models are training simultaneously, which means two optimizers, etc.
+"""
+
+import argparse
+from pathlib import Path
+
+import evaluate
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup
+
+from accelerate import Accelerator, DeepSpeedPlugin, DistributedType
+from accelerate.state import AcceleratorState
+from accelerate.utils.deepspeed import get_active_deepspeed_plugin
+
+
+EVAL_BATCH_SIZE = 16
+
+
+class NoiseModel(torch.nn.Module):
+ def __init__(self, noise_factor=0.1):
+ super().__init__()
+ self.noise_factor = torch.nn.Parameter(torch.tensor(noise_factor, dtype=torch.float32))
+
+ def forward(self, loss):
+ return loss * self.noise_factor
+
+
+def get_dataloaders(accelerator: Accelerator, batch_size: int = 16, model_name: str = "bert-base-cased"):
+ """
+ Creates a set of `DataLoader`s for the `glue` dataset.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ model_name (`str`, *optional*):
+ """
+ tokenizer = AutoTokenizer.from_pretrained(model_name)
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ tokenized_datasets = datasets.map(
+ tokenize_function, batched=True, remove_columns=["idx", "sentence1", "sentence2"], load_from_cache_file=False
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ if accelerator.distributed_type == DistributedType.XLA:
+ return tokenizer.pad(examples, padding="max_length", max_length=128, return_tensors="pt")
+ return tokenizer.pad(examples, padding="longest", return_tensors="pt")
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+test_file_path = __file__
+path = Path(test_file_path).resolve()
+test_file_dir_str = str(path.parent.parent.parent.parent.parent.parent)
+
+# Create our DS plugins
+# We use custom schedulers and optimizers, hence `model_only`
+ds_config_file = dict(
+ zero2=f"{test_file_dir_str}/tests/deepspeed/ds_config_zero2_model_only.json",
+ zero3=f"{test_file_dir_str}/tests/deepspeed/ds_config_zero3_model_only.json",
+)
+
+
+def single_model_training(config, args):
+ # Training a single model, we have a `noise` model that is untrainable used to inject some noise into the training process
+ num_epochs = config["num_epochs"]
+ zero2_plugin = DeepSpeedPlugin(hf_ds_config=ds_config_file["zero2"])
+ zero3_plugin = DeepSpeedPlugin(hf_ds_config=ds_config_file["zero3"])
+
+ deepspeed_plugins = {"training": zero2_plugin, "inference": zero3_plugin}
+
+ # Initialize accelerator
+ accelerator = Accelerator(
+ deepspeed_plugins=deepspeed_plugins,
+ mixed_precision="bf16",
+ )
+
+ # Initialize model under zero2 plugin
+ assert get_active_deepspeed_plugin(accelerator.state) is zero2_plugin
+ train_model = AutoModelForSequenceClassification.from_pretrained(args.model_name_or_path)
+ train_dataloader, eval_dataloader = get_dataloaders(
+ accelerator, batch_size=config["batch_size"], model_name=args.model_name_or_path
+ )
+ max_training_steps = len(train_dataloader) * config["num_epochs"]
+ optimizer = AdamW(train_model.parameters(), lr=config["lr"])
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer, num_warmup_steps=0, num_training_steps=max_training_steps
+ )
+
+ train_dataloader, eval_dataloader, train_model, optimizer, lr_scheduler = accelerator.prepare(
+ train_dataloader, eval_dataloader, train_model, optimizer, lr_scheduler
+ )
+
+ # Now prepare the model under zero3 plugin
+ accelerator.state.select_deepspeed_plugin("inference")
+ assert get_active_deepspeed_plugin(accelerator.state) is zero3_plugin
+ inference_model = NoiseModel()
+ inference_model = accelerator.prepare(inference_model)
+ inference_model.eval()
+
+ # Run training loop
+ accelerator.state.select_deepspeed_plugin("training")
+ # We also need to keep track of the stating epoch so files are named properly
+ starting_epoch = 0
+
+ # Now we train the model
+ best_performance = 0
+ metric = evaluate.load("glue", "mrpc")
+ performance_metric = {}
+ for epoch in range(starting_epoch, num_epochs):
+ train_model.train()
+ inference_model.train()
+ for step, batch in enumerate(train_dataloader):
+ with accelerator.accumulate(train_model):
+ outputs_1 = train_model(**batch)
+ with torch.no_grad():
+ outputs_2 = inference_model(outputs_1.loss)
+ # Combine the losses
+ loss = outputs_1.loss + outputs_2
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ train_model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = train_model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ # It is slightly faster to call this once, than multiple times
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+ performance_metric[f"epoch-{epoch}"] = eval_metric["accuracy"]
+
+ if best_performance < eval_metric["accuracy"]:
+ best_performance = eval_metric["accuracy"]
+ assert best_performance > performance_metric["epoch-0"]
+
+
+def multiple_model_training(config, args):
+ # This will essentially be like a k-fold model, but one model is Zero-2 and another model is Zero-3
+ num_epochs = config["num_epochs"]
+ zero2_plugin = DeepSpeedPlugin(hf_ds_config=ds_config_file["zero2"])
+ zero3_plugin = DeepSpeedPlugin(hf_ds_config=ds_config_file["zero3"])
+
+ deepspeed_plugins = {"zero2": zero2_plugin, "zero3": zero3_plugin}
+
+ # Initialize accelerator
+ zero2_accelerator = Accelerator(
+ deepspeed_plugins=deepspeed_plugins,
+ mixed_precision="bf16",
+ )
+
+ # Since an `AcceleratorState` has already been made, we can just reuse it here
+ zero3_accelerator = Accelerator()
+
+ # Initialize model under zero2 plugin
+ assert get_active_deepspeed_plugin(zero2_accelerator.state) is zero2_plugin
+ zero2_model = AutoModelForSequenceClassification.from_pretrained(args.model_name_or_path)
+ train_dataloader, eval_dataloader = get_dataloaders(
+ zero2_accelerator, batch_size=config["batch_size"], model_name=args.model_name_or_path
+ )
+ max_training_steps = len(train_dataloader) * config["num_epochs"]
+ zero2_optimizer = AdamW(zero2_model.parameters(), lr=config["lr"])
+ zero2_lr_scheduler = get_linear_schedule_with_warmup(
+ zero2_optimizer, num_warmup_steps=0, num_training_steps=max_training_steps
+ )
+
+ train_dataloader, eval_dataloader, zero2_model, zero2_optimizer, zero2_lr_scheduler = zero2_accelerator.prepare(
+ train_dataloader, eval_dataloader, zero2_model, zero2_optimizer, zero2_lr_scheduler
+ )
+ assert zero2_accelerator.deepspeed_engine_wrapped.engine is zero2_model
+
+ # now do Zero3
+ zero3_accelerator.state.select_deepspeed_plugin("zero3")
+ zero3_plugin.deepspeed_config["train_micro_batch_size_per_gpu"] = zero2_plugin.deepspeed_config[
+ "train_micro_batch_size_per_gpu"
+ ]
+ assert get_active_deepspeed_plugin(zero3_accelerator.state) is zero3_plugin
+ zero3_model = AutoModelForSequenceClassification.from_pretrained(args.model_name_or_path)
+ zero3_optimizer = AdamW(zero3_model.parameters(), lr=config["lr"])
+ zero3_lr_scheduler = get_linear_schedule_with_warmup(
+ zero3_optimizer, num_warmup_steps=0, num_training_steps=max_training_steps
+ )
+ zero3_model, zero3_optimizer, zero3_lr_scheduler = zero3_accelerator.prepare(
+ zero3_model, zero3_optimizer, zero3_lr_scheduler
+ )
+ assert zero3_accelerator.deepspeed_engine_wrapped.engine is zero3_model
+
+ # Run training loop
+ starting_epoch = 0
+
+ # Now we train the model
+ best_performance_a = 0
+ best_performance_b = 0
+ metric_a = evaluate.load("glue", "mrpc")
+ metric_b = evaluate.load("glue", "mrpc")
+ performance_metric_a = {}
+ performance_metric_b = {}
+ for epoch in range(starting_epoch, num_epochs):
+ zero2_model.train()
+ zero3_model.train()
+ for step, batch in enumerate(train_dataloader):
+ with zero2_accelerator.accumulate(zero2_model, zero3_model):
+ outputs_1 = zero2_model(**batch)
+ zero2_accelerator.backward(outputs_1.loss)
+ zero2_optimizer.step()
+ zero2_lr_scheduler.step()
+ zero2_optimizer.zero_grad()
+ outputs_2 = zero3_model(**batch)
+ zero3_accelerator.backward(outputs_2.loss)
+ zero3_optimizer.step()
+ zero3_lr_scheduler.step()
+ zero3_optimizer.zero_grad()
+
+ zero2_model.eval()
+ zero3_model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ logits_a = zero2_model(**batch).logits
+ logits_b = zero3_model(**batch).logits
+ # Combine the logits from both models
+ predictions_a = logits_a.argmax(dim=-1)
+ predictions_b = logits_b.argmax(dim=-1)
+ # It is slightly faster to call this once, than multiple times
+ predictions_a, predictions_b, references = zero2_accelerator.gather_for_metrics(
+ (predictions_a, predictions_b, batch["labels"])
+ )
+ metric_a.add_batch(
+ predictions=predictions_a,
+ references=references,
+ )
+ metric_b.add_batch(
+ predictions=predictions_b,
+ references=references,
+ )
+
+ eval_metric_a = metric_a.compute()
+ eval_metric_b = metric_b.compute()
+ # Use accelerator.print to print only on the main process.
+ zero2_accelerator.print(f"epoch {epoch}:", eval_metric_a, eval_metric_b)
+ performance_metric_a[f"epoch-{epoch}"] = eval_metric_a["accuracy"]
+ performance_metric_b[f"epoch-{epoch}"] = eval_metric_b["accuracy"]
+
+ if best_performance_a < eval_metric_a["accuracy"]:
+ best_performance_a = eval_metric_a["accuracy"]
+ if best_performance_b < eval_metric_b["accuracy"]:
+ best_performance_b = eval_metric_b["accuracy"]
+ assert best_performance_a > performance_metric_a["epoch-0"]
+ assert best_performance_b > performance_metric_b["epoch-0"]
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script tracking peak GPU memory usage.")
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ default="bert-base-cased",
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=False,
+ )
+ parser.add_argument(
+ "--performance_lower_bound",
+ type=float,
+ default=None,
+ help="Optional lower bound for the performance metric. If set, the training will throw error when the performance metric drops below this value.",
+ )
+ parser.add_argument(
+ "--num_epochs",
+ type=int,
+ default=3,
+ help="Number of train epochs.",
+ )
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": args.num_epochs, "seed": 42, "batch_size": 8}
+ single_model_training(config, args)
+ AcceleratorState._reset_state(True)
+ multiple_model_training(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_metrics.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_metrics.py
new file mode 100644
index 0000000000000000000000000000000000000000..d1bfe351509148ebc48067584e9d61b93e7210a6
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_metrics.py
@@ -0,0 +1,307 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import logging
+import math
+import os
+from copy import deepcopy
+
+import datasets
+import evaluate
+import torch
+import transformers
+from datasets import load_dataset
+from torch.utils.data import DataLoader, IterableDataset
+from transformers import AutoModelForSequenceClassification, AutoTokenizer
+
+from accelerate import Accelerator, DataLoaderConfiguration, DistributedType
+from accelerate.data_loader import DataLoaderDispatcher
+from accelerate.test_utils import RegressionDataset, RegressionModel, torch_device
+from accelerate.utils import is_torch_xla_available, set_seed
+
+
+os.environ["TRANSFORMERS_NO_ADVISORY_WARNINGS"] = "true"
+
+
+class ListHandler(logging.Handler):
+ def __init__(self, *args, **kwargs):
+ super().__init__(*args, **kwargs)
+ self.logs = []
+
+ def emit(self, record):
+ self.logs.append(record)
+
+
+def get_basic_setup(accelerator, num_samples=82, batch_size=16):
+ "Returns everything needed to perform basic training"
+ set_seed(42)
+ model = RegressionModel()
+ ddp_model = deepcopy(model)
+ dset = RegressionDataset(length=num_samples)
+ dataloader = DataLoader(dset, batch_size=batch_size)
+ model.to(accelerator.device)
+ ddp_model, dataloader = accelerator.prepare(ddp_model, dataloader)
+ return model, ddp_model, dataloader
+
+
+def get_dataloader(accelerator: Accelerator, use_longest=False):
+ tokenizer = AutoTokenizer.from_pretrained("hf-internal-testing/mrpc-bert-base-cased")
+ dataset = load_dataset("glue", "mrpc", split="validation")
+
+ def tokenize_function(examples):
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ with accelerator.main_process_first():
+ tokenized_datasets = dataset.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ if use_longest:
+ return tokenizer.pad(examples, padding="longest", return_tensors="pt")
+ return tokenizer.pad(examples, padding="max_length", max_length=128, return_tensors="pt")
+
+ return DataLoader(tokenized_datasets, shuffle=False, collate_fn=collate_fn, batch_size=16)
+
+
+def get_mrpc_setup(dispatch_batches, split_batches):
+ dataloader_config = DataLoaderConfiguration(dispatch_batches=dispatch_batches, split_batches=split_batches)
+ accelerator = Accelerator(dataloader_config=dataloader_config)
+ dataloader = get_dataloader(accelerator, not dispatch_batches)
+ model = AutoModelForSequenceClassification.from_pretrained(
+ "hf-internal-testing/mrpc-bert-base-cased", return_dict=True
+ )
+ ddp_model, ddp_dataloader = accelerator.prepare(model, dataloader)
+ return {
+ "ddp": [ddp_model, ddp_dataloader, torch_device],
+ "no": [model, dataloader, accelerator.device],
+ }, accelerator
+
+
+def generate_predictions(model, dataloader, accelerator):
+ logits_and_targets = []
+ for batch in dataloader:
+ input, target = batch.values()
+ with torch.no_grad():
+ logit = model(input)
+ logit, target = accelerator.gather_for_metrics((logit, target))
+ logits_and_targets.append((logit, target))
+ logits, targs = [], []
+ for logit, targ in logits_and_targets:
+ logits.append(logit)
+ targs.append(targ)
+ logits, targs = torch.cat(logits), torch.cat(targs)
+ return logits, targs
+
+
+def test_torch_metrics(
+ accelerator: Accelerator, num_samples=82, dispatch_batches=False, split_batches=False, batch_size=16
+):
+ _, ddp_model, dataloader = get_basic_setup(accelerator, num_samples, batch_size)
+ logits, _ = generate_predictions(ddp_model, dataloader, accelerator)
+ assert len(logits) == num_samples, (
+ f"Unexpected number of inputs:\n Expected: {num_samples}\n Actual: {len(logits)}"
+ )
+
+
+def test_mrpc(dispatch_batches: bool = False, split_batches: bool = False):
+ metric = evaluate.load("glue", "mrpc")
+ setup, accelerator = get_mrpc_setup(dispatch_batches, split_batches)
+ # First do baseline
+ model, dataloader, device = setup["no"]
+ model.to(device)
+ model.eval()
+ for batch in dataloader:
+ batch.to(device)
+ with torch.inference_mode():
+ outputs = model(**batch)
+ preds = outputs.logits.argmax(dim=-1)
+ metric.add_batch(predictions=preds, references=batch["labels"])
+ baseline = metric.compute()
+
+ # Then do distributed
+ model, dataloader, device = setup["ddp"]
+ model.eval()
+ for batch in dataloader:
+ with torch.inference_mode():
+ outputs = model(**batch)
+ preds = outputs.logits.argmax(dim=-1)
+ references = batch["labels"]
+ preds, references = accelerator.gather_for_metrics((preds, references))
+ metric.add_batch(predictions=preds, references=references)
+ distributed = metric.compute()
+
+ for key in "accuracy f1".split():
+ assert math.isclose(baseline[key], distributed[key]), (
+ f"Baseline and Distributed are not the same for key {key}:\n\tBaseline: {baseline[key]}\n\tDistributed: {distributed[key]}\n"
+ )
+
+
+def test_gather_for_metrics_with_non_tensor_objects_iterable_dataset():
+ class DummyIterableDataset(IterableDataset):
+ def __init__(self, data):
+ self.data = data
+
+ def __len__(self):
+ return len(self.data)
+
+ def __iter__(self):
+ yield from self.data
+
+ iterable_dataset = DummyIterableDataset([n for n in range(30)])
+ dataloader = DataLoader(iterable_dataset, batch_size=4)
+ accelerator = Accelerator()
+ prepared_dataloader = accelerator.prepare(dataloader)
+
+ if accelerator.is_main_process:
+ logger = logging.root.manager.loggerDict["accelerate.accelerator"]
+ list_handler = ListHandler()
+ logger.addHandler(list_handler)
+
+ batches_for_metrics = []
+ for batch in prepared_dataloader:
+ batches_for_metrics.append(accelerator.gather_for_metrics(batch))
+
+ assert torch.cat(batches_for_metrics).size(0) == 30
+
+ if accelerator.is_main_process:
+ assert len(list_handler.logs) == 0
+ logger.removeHandler(list_handler)
+
+
+def test_gather_for_metrics_with_iterable_dataset():
+ class DummyIterableDataset(IterableDataset):
+ def __init__(self, data):
+ self.data = data
+
+ def __len__(self):
+ return len(self.data)
+
+ def __iter__(self):
+ yield from self.data
+
+ iterable_dataset = DummyIterableDataset(torch.as_tensor(range(30)))
+ dataloader = DataLoader(iterable_dataset, batch_size=4)
+
+ accelerator = Accelerator()
+ prepared_dataloader = accelerator.prepare(dataloader)
+
+ assert isinstance(prepared_dataloader, DataLoaderDispatcher)
+
+ if accelerator.is_main_process:
+ logger = logging.root.manager.loggerDict["accelerate.accelerator"]
+ list_handler = ListHandler()
+ logger.addHandler(list_handler)
+
+ batches_for_metrics = []
+ for batch in prepared_dataloader:
+ batches_for_metrics.append(accelerator.gather_for_metrics(batch))
+
+ assert torch.cat(batches_for_metrics).size(0) == 30
+
+ if accelerator.is_main_process:
+ assert len(list_handler.logs) == 0
+
+ logger.removeHandler(list_handler)
+
+
+def test_gather_for_metrics_drop_last():
+ accelerator = Accelerator()
+ per_device_batch_size = 5
+ num_items = (10 * accelerator.num_processes) + 1
+ dataloader = DataLoader(range(num_items), batch_size=per_device_batch_size, drop_last=True)
+ dataloader = accelerator.prepare(dataloader)
+
+ iterator = iter(dataloader)
+ next(iterator) # Skip first batch tensor([0, 1, 2, 3, 4], device='cuda:0')
+ batch = next(iterator)
+ gathered_items = accelerator.gather_for_metrics(batch)
+
+ # Should return a full set of complete batches from each GPU
+ num_expected_items = per_device_batch_size * accelerator.num_processes
+ assert gathered_items.size(0) == (num_expected_items), (
+ f"Expected number of items: {num_expected_items}, Actual: {gathered_items.size(0)}"
+ )
+
+
+def main():
+ dataloader_config = DataLoaderConfiguration(split_batches=False, dispatch_batches=False)
+ accelerator = Accelerator(dataloader_config=dataloader_config)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_warning()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+ # TorchXLA does not support batch dispatching. 'put_on_device' is always False for
+ # TorchXLA, which can cause a value error in 'prepare_data_loader' function.
+ dispatch_batches_options = [False] if accelerator.state.distributed_type == DistributedType.XLA else [True, False]
+
+ # Temporarily close this test for TorchXLA due to the 'Cannot set version_counter for
+ # inference tensor' error in inference mode. Reopen it after TorchXLA fixes this bug.
+ # These are a bit slower so they should only be ran on the GPU or TPU
+ if accelerator.device.type != "cpu" and not is_torch_xla_available():
+ if accelerator.is_local_main_process:
+ print("**Testing gather_for_metrics**")
+ for split_batches in [True, False]:
+ for dispatch_batches in dispatch_batches_options:
+ if accelerator.is_local_main_process:
+ print(f"With: `split_batches={split_batches}`, `dispatch_batches={dispatch_batches}`")
+ test_mrpc(dispatch_batches, split_batches)
+ accelerator.state._reset_state()
+ print("test_gather_for_metrics_with_iterable_dataset")
+ test_gather_for_metrics_with_iterable_dataset()
+ print("test gather_for_metrics_with_non_tensor_objects_iterable_dataset")
+ test_gather_for_metrics_with_non_tensor_objects_iterable_dataset()
+
+ # MpDeviceLoader in TorchXLA is an asynchronous loader that preloads several batches into cache.
+ # This can cause the 'end_of_dataloader' of DataLoaderStateMixin to be set earlier than intended.
+ # Skip this test when TorchXLA is enabled.
+ if accelerator.state.distributed_type != DistributedType.XLA:
+ if accelerator.is_local_main_process:
+ print("**Test torch metrics**")
+ for split_batches in [True, False]:
+ for dispatch_batches in dispatch_batches_options:
+ dataloader_config = DataLoaderConfiguration(
+ split_batches=split_batches, dispatch_batches=dispatch_batches
+ )
+ accelerator = Accelerator(dataloader_config=dataloader_config)
+ if accelerator.is_local_main_process:
+ print(f"With: `split_batches={split_batches}`, `dispatch_batches={dispatch_batches}`, length=99")
+ test_torch_metrics(accelerator, 99)
+ accelerator.state._reset_state()
+ if accelerator.is_local_main_process:
+ print("**Test last batch is not dropped when perfectly divisible**")
+ accelerator = Accelerator()
+ test_torch_metrics(accelerator, 512)
+ accelerator.state._reset_state()
+ if accelerator.is_local_main_process:
+ print("**Test that `drop_last` is taken into account**")
+ test_gather_for_metrics_drop_last()
+ accelerator.end_training()
+ accelerator.state._reset_state()
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_peak_memory_usage.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_peak_memory_usage.py
new file mode 100644
index 0000000000000000000000000000000000000000..e1b59afec5c5de3d54bf26c8844dd8f9e6983f61
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_peak_memory_usage.py
@@ -0,0 +1,314 @@
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import gc
+import json
+import os
+
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup, set_seed
+
+from accelerate import Accelerator, DistributedType
+from accelerate.utils import (
+ is_hpu_available,
+ is_mlu_available,
+ is_musa_available,
+ is_npu_available,
+ is_sdaa_available,
+ is_xpu_available,
+)
+from accelerate.utils.deepspeed import DummyOptim, DummyScheduler
+
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+
+# Converting Bytes to Megabytes
+def b2mb(x):
+ return int(x / 2**20)
+
+
+# This context manager is used to track the peak memory usage of the process
+class TorchTracemalloc:
+ def __enter__(self):
+ gc.collect()
+ if torch.cuda.is_available():
+ torch.cuda.empty_cache()
+ torch.cuda.reset_max_memory_allocated() # reset the peak gauge to zero
+ self.begin = torch.cuda.memory_allocated()
+ elif is_mlu_available():
+ torch.mlu.empty_cache()
+ torch.mlu.reset_max_memory_allocated() # reset the peak gauge to zero
+ self.begin = torch.mlu.memory_allocated()
+ elif is_sdaa_available():
+ torch.sdaa.empty_cache()
+ torch.sdaa.reset_max_memory_allocated() # reset the peak gauge to zero
+ self.begin = torch.sdaa.memory_allocated()
+ elif is_musa_available():
+ torch.musa.empty_cache()
+ torch.musa.reset_max_memory_allocated() # reset the peak gauge to zero
+ self.begin = torch.musa.memory_allocated()
+ elif is_npu_available():
+ torch.npu.empty_cache()
+ torch.npu.reset_max_memory_allocated() # reset the peak gauge to zero
+ self.begin = torch.npu.memory_allocated()
+ elif is_xpu_available():
+ torch.xpu.empty_cache()
+ torch.xpu.reset_peak_memory_stats() # reset the peak gauge to zero
+ self.begin = torch.xpu.memory_allocated()
+ elif is_hpu_available():
+ # torch.hpu.empty_cache() # not available on hpu as it reserves all device memory for the current process
+ torch.hpu.reset_peak_memory_stats() # reset the peak gauge to zero
+ self.begin = torch.hpu.memory_allocated()
+ return self
+
+ def __exit__(self, *exc):
+ gc.collect()
+ if torch.cuda.is_available():
+ torch.cuda.empty_cache()
+ self.end = torch.cuda.memory_allocated()
+ self.peak = torch.cuda.max_memory_allocated()
+ elif is_mlu_available():
+ torch.mlu.empty_cache()
+ self.end = torch.mlu.memory_allocated()
+ self.begin = torch.mlu.max_memory_allocated()
+ elif is_sdaa_available():
+ torch.sdaa.empty_cache()
+ self.end = torch.sdaa.memory_allocated()
+ self.begin = torch.sdaa.max_memory_allocated()
+ elif is_musa_available():
+ torch.musa.empty_cache()
+ self.end = torch.musa.memory_allocated()
+ self.begin = torch.musa.max_memory_allocated()
+ elif is_npu_available():
+ torch.npu.empty_cache()
+ self.end = torch.npu.memory_allocated()
+ self.peak = torch.npu.max_memory_allocated()
+ elif is_xpu_available():
+ torch.xpu.empty_cache()
+ self.end = torch.xpu.memory_allocated()
+ self.peak = torch.xpu.max_memory_allocated()
+ elif is_hpu_available():
+ # torch.hpu.empty_cache() # not available on hpu as it reserves all device memory for the current process
+ self.end = torch.hpu.memory_allocated()
+ self.peak = torch.hpu.max_memory_allocated()
+ self.used = b2mb(self.end - self.begin)
+ self.peaked = b2mb(self.peak - self.begin)
+ # print(f"delta used/peak {self.used:4d}/{self.peaked:4d}")
+
+
+def get_dataloaders(
+ accelerator: Accelerator,
+ batch_size: int = 16,
+ model_name: str = "bert-base-cased",
+ n_train: int = 320,
+ n_val: int = 160,
+):
+ """
+ Creates a set of `DataLoader`s for the `glue` dataset.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ model_name (`str`, *optional*):
+ The name of the model to use.
+ n_train (`int`, *optional*):
+ The number of training examples to use.
+ n_val (`int`, *optional*):
+ The number of validation examples to use.
+ """
+ tokenizer = AutoTokenizer.from_pretrained(model_name)
+ datasets = load_dataset(
+ "glue", "mrpc", split={"train": f"train[:{n_train}]", "validation": f"validation[:{n_val}]"}
+ )
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ tokenized_datasets = datasets.map(
+ tokenize_function, batched=True, remove_columns=["idx", "sentence1", "sentence2"], load_from_cache_file=False
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ if accelerator.distributed_type == DistributedType.XLA:
+ return tokenizer.pad(examples, padding="max_length", max_length=128, return_tensors="pt")
+ return tokenizer.pad(examples, padding="longest", return_tensors="pt")
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+def training_function(config, args):
+ # Initialize accelerator
+ accelerator = Accelerator()
+
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+ model_name = args.model_name_or_path
+
+ set_seed(seed)
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size, model_name, args.n_train, args.n_val)
+
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained(model_name, return_dict=True)
+
+ # Instantiate optimizer
+ optimizer_cls = (
+ AdamW
+ if accelerator.state.deepspeed_plugin is None
+ or "optimizer" not in accelerator.state.deepspeed_plugin.deepspeed_config
+ else DummyOptim
+ )
+ optimizer = optimizer_cls(params=model.parameters(), lr=lr)
+
+ if accelerator.state.deepspeed_plugin is not None:
+ gradient_accumulation_steps = accelerator.state.deepspeed_plugin.deepspeed_config[
+ "gradient_accumulation_steps"
+ ]
+ else:
+ gradient_accumulation_steps = 1
+ max_training_steps = (len(train_dataloader) * num_epochs) // gradient_accumulation_steps
+
+ # Instantiate scheduler
+ if (
+ accelerator.state.deepspeed_plugin is None
+ or "scheduler" not in accelerator.state.deepspeed_plugin.deepspeed_config
+ ):
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=0,
+ num_training_steps=max_training_steps,
+ )
+ else:
+ lr_scheduler = DummyScheduler(optimizer, total_num_steps=max_training_steps, warmup_num_steps=0)
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # We need to keep track of how many total steps we have iterated over
+ overall_step = 0
+ # We also need to keep track of the stating epoch so files are named properly
+ starting_epoch = 0
+
+ # Now we train the model
+ train_total_peak_memory = {}
+ for epoch in range(starting_epoch, num_epochs):
+ with TorchTracemalloc() as tracemalloc:
+ model.train()
+ for step, batch in enumerate(train_dataloader):
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss = loss / gradient_accumulation_steps
+ accelerator.backward(loss)
+ if step % gradient_accumulation_steps == 0:
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ overall_step += 1
+
+ # Printing the GPU memory usage details such as allocated memory, peak memory, and total memory usage
+ accelerator.print(f"Memory before entering the train : {b2mb(tracemalloc.begin)}")
+ accelerator.print(f"Memory consumed at the end of the train (end-begin): {tracemalloc.used}")
+ accelerator.print(f"Peak Memory consumed during the train (max-begin): {tracemalloc.peaked}")
+ accelerator.print(
+ f"Total Peak Memory consumed during the train (max): {tracemalloc.peaked + b2mb(tracemalloc.begin)}"
+ )
+ train_total_peak_memory[f"epoch-{epoch}"] = tracemalloc.peaked + b2mb(tracemalloc.begin)
+ if args.peak_memory_upper_bound is not None:
+ assert train_total_peak_memory[f"epoch-{epoch}"] <= args.peak_memory_upper_bound, (
+ "Peak memory usage exceeded the upper bound"
+ )
+
+ accelerator.wait_for_everyone()
+ if accelerator.is_main_process:
+ with open(os.path.join(args.output_dir, "peak_memory_utilization.json"), "w") as f:
+ json.dump(train_total_peak_memory, f)
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script tracking peak GPU memory usage.")
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ default="bert-base-cased",
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=False,
+ )
+ parser.add_argument(
+ "--output_dir",
+ type=str,
+ default=".",
+ help="Optional save directory where all checkpoint folders will be stored. Default is the current working directory.",
+ )
+ parser.add_argument(
+ "--peak_memory_upper_bound",
+ type=float,
+ default=None,
+ help="The upper bound of peak memory usage in MB. If set, the training will throw an error if the peak memory usage exceeds this value.",
+ )
+ parser.add_argument(
+ "--n_train",
+ type=int,
+ default=320,
+ help="Number of training examples to use.",
+ )
+ parser.add_argument(
+ "--n_val",
+ type=int,
+ default=160,
+ help="Number of validation examples to use.",
+ )
+ parser.add_argument(
+ "--num_epochs",
+ type=int,
+ default=1,
+ help="Number of train epochs.",
+ )
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": args.num_epochs, "seed": 42, "batch_size": 16}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_performance.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_performance.py
new file mode 100644
index 0000000000000000000000000000000000000000..8e500bdd4c01013904375f010e99d22aea4e4ff9
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_performance.py
@@ -0,0 +1,299 @@
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import json
+import os
+from contextlib import nullcontext
+from pathlib import Path
+
+import evaluate
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup
+
+from accelerate import Accelerator, DistributedType
+from accelerate.parallelism_config import ParallelismConfig
+from accelerate.utils import SAFE_WEIGHTS_NAME, set_seed
+from accelerate.utils.deepspeed import DummyOptim, DummyScheduler
+
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+
+def get_dataloaders(accelerator: Accelerator, batch_size: int = 16, model_name: str = "bert-base-cased"):
+ """
+ Creates a set of `DataLoader`s for the `glue` dataset.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ model_name (`str`, *optional*):
+ """
+ tokenizer = AutoTokenizer.from_pretrained(model_name)
+
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ tokenized_datasets = datasets.map(
+ tokenize_function, batched=True, remove_columns=["idx", "sentence1", "sentence2"], load_from_cache_file=False
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ if accelerator.distributed_type == DistributedType.XLA:
+ return tokenizer.pad(examples, padding="max_length", max_length=128, return_tensors="pt")
+ return tokenizer.pad(examples, padding="longest", return_tensors="pt")
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+def training_function(config, args):
+ accelerator_kwargs = {}
+ # need this for DeepSpeed tests as `args.tp_size` would be None and `torch.distributed.init_device_mesh` would fail
+ if args.tp_size is not None:
+ accelerator_kwargs["parallelism_config"] = ParallelismConfig(tp_size=args.tp_size)
+
+ # Initialize accelerator
+ accelerator = Accelerator(**accelerator_kwargs)
+
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+ model_name = args.model_name_or_path
+
+ set_seed(seed)
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size, model_name)
+
+ # Add TP related kwargs if provided
+ model_kwargs = {}
+ if args.tp_plan is not None:
+ model_kwargs["tp_plan"] = args.tp_plan
+ if args.tp_size is not None:
+ model_kwargs["tp_size"] = args.tp_size
+
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained(model_name, return_dict=True, **model_kwargs)
+
+ if args.add_pad_token:
+ if model.config.pad_token_id is None:
+ model.config.pad_token_id = 0
+
+ # Instantiate optimizer
+ optimizer_cls = (
+ AdamW
+ if accelerator.state.deepspeed_plugin is None
+ or "optimizer" not in accelerator.state.deepspeed_plugin.deepspeed_config
+ else DummyOptim
+ )
+ optimizer = optimizer_cls(params=model.parameters(), lr=lr)
+
+ max_training_steps = len(train_dataloader) * num_epochs
+
+ # Instantiate scheduler
+ linear_decay_scheduler = False
+ if (
+ accelerator.state.deepspeed_plugin is None
+ or "scheduler" not in accelerator.state.deepspeed_plugin.deepspeed_config
+ ):
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=0,
+ num_training_steps=max_training_steps,
+ )
+ linear_decay_scheduler = True
+ else:
+ lr_scheduler = DummyScheduler(optimizer, total_num_steps=max_training_steps, warmup_num_steps=0)
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # We also need to keep track of the stating epoch so files are named properly
+ starting_epoch = 0
+
+ # Now we train the model
+ metric = evaluate.load("glue", "mrpc")
+ best_performance = 0
+ performance_metric = {}
+ expected_lr_after_first_optim_step = lr * (
+ 1 - 1 / (max_training_steps / accelerator.num_processes / accelerator.gradient_accumulation_steps)
+ )
+ lr_scheduler_check_completed = False
+ for epoch in range(starting_epoch, num_epochs):
+ model.train()
+ for step, batch in enumerate(train_dataloader):
+ with accelerator.accumulate(model):
+ outputs = model(**batch)
+ loss = outputs.loss
+ accelerator.backward(loss)
+ context = nullcontext
+ if args.tp_plan is not None:
+ from torch.distributed._tensor.experimental import implicit_replication
+
+ context = implicit_replication
+ with context():
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # assert the learning rate after first optimizer step
+ if (
+ accelerator.sync_gradients
+ and not lr_scheduler_check_completed
+ and linear_decay_scheduler
+ and accelerator.state.mixed_precision == "no"
+ ):
+ assert lr_scheduler.get_last_lr()[0] == expected_lr_after_first_optim_step, (
+ f"Wrong lr found at second step, expected {expected_lr_after_first_optim_step}, got {lr_scheduler.get_last_lr()[0]}"
+ )
+ lr_scheduler_check_completed = True
+
+ model.eval()
+ samples_seen = 0
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ # It is slightly faster to call this once, than multiple times
+ predictions, references = accelerator.gather(
+ (predictions, batch["labels"])
+ ) # If we are in a multiprocess environment, the last batch has duplicates
+ if accelerator.use_distributed:
+ if step == len(eval_dataloader) - 1:
+ predictions = predictions[: len(eval_dataloader.dataset) - samples_seen]
+ references = references[: len(eval_dataloader.dataset) - samples_seen]
+ else:
+ samples_seen += references.shape[0]
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+ performance_metric[f"epoch-{epoch}"] = eval_metric["accuracy"]
+
+ if best_performance < eval_metric["accuracy"]:
+ best_performance = eval_metric["accuracy"]
+
+ # check that the LR is 0
+ if linear_decay_scheduler and accelerator.state.mixed_precision == "no":
+ assert lr_scheduler.get_last_lr()[0] == 0, (
+ f"Wrong lr found at last step, expected 0, got {lr_scheduler.get_last_lr()[0]}"
+ )
+
+ if args.performance_lower_bound is not None:
+ assert args.performance_lower_bound <= best_performance, (
+ f"Best performance metric {best_performance} is lower than the lower bound {args.performance_lower_bound}"
+ )
+
+ accelerator.wait_for_everyone()
+ if accelerator.is_main_process:
+ with open(os.path.join(args.output_dir, "all_results.json"), "w") as f:
+ json.dump(performance_metric, f)
+
+ # TODO: skip saving of the model test for TP until the feature lands
+ if args.tp_plan is None:
+ # Finally try saving the model
+ accelerator.save_model(model, args.output_dir)
+ accelerator.wait_for_everyone()
+ if args.tp_plan is None:
+ assert Path(args.output_dir, SAFE_WEIGHTS_NAME).exists(), (
+ "Model was not saved when calling `Accelerator.save_model`"
+ )
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script tracking peak GPU memory usage.")
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ default="bert-base-cased",
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=False,
+ )
+ parser.add_argument(
+ "--output_dir",
+ type=str,
+ default=".",
+ help="Optional save directory where all checkpoint folders will be stored. Default is the current working directory.",
+ )
+ parser.add_argument(
+ "--performance_lower_bound",
+ type=float,
+ default=None,
+ help="Optional lower bound for the performance metric. If set, the training will throw error when the performance metric drops below this value.",
+ )
+ parser.add_argument(
+ "--num_epochs",
+ type=int,
+ default=3,
+ help="Number of train epochs.",
+ )
+ parser.add_argument(
+ "--add_pad_token",
+ type=bool,
+ default=False,
+ help="To add pad token if not exists.",
+ )
+ parser.add_argument(
+ "--tp_plan",
+ type=str,
+ default=None,
+ help="pass 'auto' to use TP",
+ )
+ parser.add_argument(
+ "--tp_size",
+ type=int,
+ default=None,
+ help="TP size to be used to shard the model",
+ )
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": args.num_epochs, "seed": 42, "batch_size": 16}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_pippy.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_pippy.py
new file mode 100644
index 0000000000000000000000000000000000000000..1dbd86c46b4a0c12df8ea4d736c7cd1e03f81813
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_pippy.py
@@ -0,0 +1,117 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import torch
+from transformers import (
+ BertConfig,
+ BertForMaskedLM,
+ GPT2Config,
+ GPT2ForSequenceClassification,
+)
+
+from accelerate import PartialState
+from accelerate.inference import prepare_pippy
+from accelerate.test_utils import torch_device
+from accelerate.utils import DistributedType, set_seed
+
+
+model_to_config = {
+ "bert": (BertForMaskedLM, BertConfig, 512),
+ "gpt2": (GPT2ForSequenceClassification, GPT2Config, 1024),
+}
+
+
+def get_model_and_data_for_text(model_name, device, num_processes: int = 2):
+ initializer, config, seq_len = model_to_config[model_name]
+ config_args = {}
+ # Eventually needed for batch inference tests on gpt-2 when bs != 1
+ # if model_name == "gpt2":
+ # config_args["pad_token_id"] = 0
+ model_config = config(**config_args)
+ model = initializer(model_config)
+ kwargs = dict(low=0, high=model_config.vocab_size, device=device, dtype=torch.int64, requires_grad=False)
+ trace_input = torch.randint(size=(1, seq_len), **kwargs)
+ inference_inputs = torch.randint(size=(num_processes, seq_len), **kwargs)
+ return model, trace_input, inference_inputs
+
+
+def test_bert(batch_size: int = 2):
+ set_seed(42)
+ state = PartialState()
+ model, trace_input, inference_inputs = get_model_and_data_for_text("bert", "cpu", batch_size)
+ model = prepare_pippy(model, example_args=(trace_input,), no_split_module_classes=model._no_split_modules)
+ # For inference args need to be a tuple
+ inputs = inference_inputs.to(torch_device)
+ with torch.no_grad():
+ output = model(inputs)
+ # Zach: Check that we just grab the real outputs we need at the end
+ if not state.is_last_process:
+ assert output is None, "Output was not generated on just the last process!"
+ else:
+ assert output is not None, "Output was not generated in the last process!"
+
+
+def test_gpt2(batch_size: int = 2):
+ set_seed(42)
+ state = PartialState()
+ model, trace_input, inference_inputs = get_model_and_data_for_text("gpt2", "cpu", batch_size)
+ model = prepare_pippy(model, example_args=(trace_input,), no_split_module_classes=model._no_split_modules)
+ # For inference args need to be a tuple
+ inputs = inference_inputs.to(torch_device)
+ with torch.no_grad():
+ output = model(inputs)
+ # Zach: Check that we just grab the real outputs we need at the end
+ if not state.is_last_process:
+ assert output is None, "Output was not generated on just the last process!"
+ else:
+ assert output is not None, "Output was not generated in the last process!"
+
+
+# Currently disabled, enable again once PyTorch pippy interface can trace a resnet34
+# def test_resnet(batch_size: int = 2):
+# set_seed(42)
+# state = PartialState()
+# model = resnet34()
+# input_tensor = torch.rand(1, 3, 224, 224)
+# model = prepare_pippy(
+# model,
+# example_args=(input_tensor,),
+# )
+# inference_inputs = torch.rand(batch_size, 3, 224, 224)
+# inputs = send_to_device(inference_inputs, torch_device)
+# with torch.no_grad():
+# output = model(inputs)
+# # Zach: Check that we just grab the real outputs we need at the end
+# if not state.is_last_process:
+# assert output is None, "Output was not generated on just the last process!"
+# else:
+# assert output is not None, "Output was not generated in the last process!"
+
+
+if __name__ == "__main__":
+ state = PartialState()
+ state.print("Testing pippy integration...")
+ try:
+ if state.distributed_type in [DistributedType.MULTI_GPU, DistributedType.MULTI_XPU, DistributedType.MULTI_HPU]:
+ state.print("Testing GPT2...")
+ test_gpt2()
+ # Issue: When modifying the tokenizer for batch GPT2 inference, there's an issue
+ # due to references
+ # NameError: cannot access free variable 'chunk_args_list' where it is not associated with a value in enclosing scope
+ # test_gpt2(3)
+ state.print("Testing BERT...")
+ test_bert()
+ else:
+ print("Less than two GPUs found, not running tests!")
+ finally:
+ state.destroy_process_group()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_zero3_integration.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_zero3_integration.py
new file mode 100644
index 0000000000000000000000000000000000000000..f6e46d342a0c754cf1ed5b2629290d62e7c943aa
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/external_deps/test_zero3_integration.py
@@ -0,0 +1,59 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import torch.distributed
+
+from accelerate.test_utils import require_huggingface_suite, torch_device
+from accelerate.utils import is_transformers_available
+
+
+if is_transformers_available():
+ from transformers import AutoModel, TrainingArguments
+
+
+GPT2_TINY = "sshleifer/tiny-gpt2"
+
+
+@require_huggingface_suite
+def init_torch_dist_then_launch_deepspeed():
+ if torch_device == "xpu":
+ backend = "xccl"
+ elif torch_device == "hpu":
+ backend = "hccl"
+ else:
+ backend = "nccl"
+
+ torch.distributed.init_process_group(backend=backend)
+ deepspeed_config = {
+ "zero_optimization": {
+ "stage": 3,
+ },
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ }
+ train_args = TrainingArguments(
+ output_dir="./",
+ deepspeed=deepspeed_config,
+ )
+ model = AutoModel.from_pretrained(GPT2_TINY)
+ assert train_args is not None
+ assert model is not None
+
+
+def main():
+ init_torch_dist_then_launch_deepspeed()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_cli.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_cli.py
new file mode 100644
index 0000000000000000000000000000000000000000..fc9dd1d36e8f2949d6e3cebb8ce65efbf0b9e5e4
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_cli.py
@@ -0,0 +1,32 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import torch
+
+from accelerate.utils import is_xpu_available
+
+
+def main():
+ accelerator_type = "GPU"
+ num_accelerators = 0
+ if torch.cuda.is_available():
+ num_accelerators = torch.cuda.device_count()
+ accelerator_type = "GPU"
+ elif is_xpu_available():
+ num_accelerators = torch.xpu.device_count()
+ accelerator_type = "XPU"
+ print(f"Successfully ran on {num_accelerators} {accelerator_type}s")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_ddp_comm_hook.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_ddp_comm_hook.py
new file mode 100644
index 0000000000000000000000000000000000000000..0db5844e026d1c035670e518a8f81d33136ea665
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_ddp_comm_hook.py
@@ -0,0 +1,85 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import torch
+
+from accelerate import Accelerator, DDPCommunicationHookType, DistributedDataParallelKwargs, PartialState
+from accelerate.utils import is_hpu_available
+
+
+class MockModel(torch.nn.Module):
+ def __init__(self):
+ super().__init__()
+ torch.manual_seed(0)
+ self.p = torch.nn.Parameter(torch.randn(40, 20))
+
+ def forward(self, x, rank):
+ return self.p * (x ** (1 + rank))
+
+
+def _run_and_get_grads(model, rank):
+ torch.manual_seed(2024)
+ input = torch.randn(40, 20)
+ output = model(input, rank)
+ output.mean().backward()
+ param = next(model.parameters())
+ return param.grad
+
+
+def test_ddp_comm_hook(comm_hook, comm_wrapper, comm_state_option):
+ ddp_kwargs = DistributedDataParallelKwargs(
+ comm_hook=comm_hook,
+ comm_wrapper=comm_wrapper,
+ comm_state_option=comm_state_option,
+ )
+ accelerator = Accelerator(kwargs_handlers=[ddp_kwargs])
+
+ model = accelerator.prepare(MockModel())
+ hook_grads = _run_and_get_grads(model, accelerator.local_process_index)
+
+ reference_model = torch.nn.parallel.DistributedDataParallel(
+ MockModel().to(accelerator.device),
+ device_ids=[accelerator.local_process_index],
+ output_device=accelerator.local_process_index,
+ )
+ reference_grads = _run_and_get_grads(reference_model, accelerator.local_process_index)
+
+ torch.testing.assert_close(hook_grads, reference_grads, rtol=1e-2, atol=1e-2)
+
+
+def main():
+ for comm_hook, comm_wrapper, comm_state_option in [
+ (DDPCommunicationHookType.NO, DDPCommunicationHookType.NO, {}),
+ (DDPCommunicationHookType.FP16, DDPCommunicationHookType.NO, {}),
+ (DDPCommunicationHookType.BF16, DDPCommunicationHookType.NO, {}),
+ (DDPCommunicationHookType.POWER_SGD, DDPCommunicationHookType.NO, {}),
+ (DDPCommunicationHookType.POWER_SGD, DDPCommunicationHookType.FP16, {}),
+ (DDPCommunicationHookType.POWER_SGD, DDPCommunicationHookType.BF16, {}),
+ (DDPCommunicationHookType.POWER_SGD, DDPCommunicationHookType.NO, {"matrix_approximation_rank": 2}),
+ (DDPCommunicationHookType.BATCHED_POWER_SGD, DDPCommunicationHookType.NO, {}),
+ (DDPCommunicationHookType.BATCHED_POWER_SGD, DDPCommunicationHookType.FP16, {}),
+ (DDPCommunicationHookType.BATCHED_POWER_SGD, DDPCommunicationHookType.BF16, {}),
+ ]:
+ if is_hpu_available():
+ HPU_UNSUPPORTED_COMM_HOOKS = {DDPCommunicationHookType.FP16, DDPCommunicationHookType.BF16}
+ if comm_hook in HPU_UNSUPPORTED_COMM_HOOKS or comm_wrapper in HPU_UNSUPPORTED_COMM_HOOKS:
+ print(f"Skipping test DDP comm hook: {comm_hook}, comm wrapper: {comm_wrapper} on HPU")
+ continue
+
+ print(f"Test DDP comm hook: {comm_hook}, comm wrapper: {comm_wrapper}")
+ test_ddp_comm_hook(comm_hook, comm_wrapper, comm_state_option)
+ PartialState().destroy_process_group()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_distributed_data_loop.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_distributed_data_loop.py
new file mode 100644
index 0000000000000000000000000000000000000000..08cbbeb844bcc3189c99d328580c251aeafc2052
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_distributed_data_loop.py
@@ -0,0 +1,410 @@
+#!/usr/bin/env python
+
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import pickle
+import tempfile
+import warnings
+from unittest.mock import Mock
+
+import torch
+from torch.utils.data import (
+ BatchSampler,
+ DataLoader,
+ Dataset,
+ IterableDataset,
+ RandomSampler,
+ TensorDataset,
+ default_collate,
+)
+
+from accelerate.accelerator import Accelerator, DataLoaderConfiguration
+from accelerate.utils.dataclasses import DistributedType
+
+
+NUM_ELEMENTS = 22
+NUM_WORKERS = 4
+BATCH_SIZE = 4
+
+
+class DummyDataset(Dataset):
+ def __len__(self):
+ return NUM_ELEMENTS
+
+ def __getitem__(self, index):
+ squeeze = False
+
+ if isinstance(index, int):
+ index = [index]
+ squeeze = True
+ elif isinstance(index, slice):
+ index = list(range(*index.indices(self.size)))
+ else:
+ index = list(index)
+
+ batch = [{"index": i, "label": i % 2, "random_augmentation": torch.rand(1).item()} for i in index]
+
+ if squeeze:
+ batch = batch[0]
+
+ return batch
+
+
+class DummyIterableDataset(IterableDataset):
+ def __init__(self, data):
+ self.data = data
+
+ def __iter__(self):
+ yield from self.data
+
+
+def create_accelerator(even_batches=True):
+ dataloader_config = DataLoaderConfiguration(even_batches=even_batches)
+ accelerator = Accelerator(dataloader_config=dataloader_config)
+ assert accelerator.num_processes == 2, "this script expects that two GPUs are available"
+ return accelerator
+
+
+def create_dataloader(
+ accelerator: Accelerator, dataset_size: int, batch_size: int, iterable: bool = False, shuffle: bool = False
+):
+ """
+ Create a simple DataLoader to use during the test cases
+ """
+ values = torch.as_tensor(range(dataset_size))
+ if shuffle:
+ values = values[torch.randperm(values.size(0))]
+ if iterable:
+ dataset = DummyIterableDataset(values)
+ else:
+ dataset = TensorDataset(torch.as_tensor(range(dataset_size)))
+
+ dl = DataLoader(dataset, batch_size=batch_size)
+ dl = accelerator.prepare(dl)
+
+ return dl
+
+
+def verify_dataloader_batch_sizes(
+ accelerator: Accelerator,
+ dataset_size: int,
+ batch_size: int,
+ process_0_expected_batch_sizes: list[int],
+ process_1_expected_batch_sizes: list[int],
+):
+ """
+ A helper function for verifying the batch sizes coming from a prepared dataloader in each process
+ """
+ dl = create_dataloader(accelerator=accelerator, dataset_size=dataset_size, batch_size=batch_size)
+
+ batch_sizes = [len(batch[0]) for batch in dl]
+
+ if accelerator.process_index == 0:
+ assert batch_sizes == process_0_expected_batch_sizes
+ elif accelerator.process_index == 1:
+ assert batch_sizes == process_1_expected_batch_sizes
+
+
+def test_default_ensures_even_batch_sizes():
+ accelerator = create_accelerator()
+
+ # without padding, we would expect a different number of batches
+ verify_dataloader_batch_sizes(
+ accelerator,
+ dataset_size=3,
+ batch_size=1,
+ process_0_expected_batch_sizes=[1, 1],
+ process_1_expected_batch_sizes=[1, 1],
+ )
+
+ # without padding, we would expect the same number of batches, but different sizes
+ verify_dataloader_batch_sizes(
+ accelerator,
+ dataset_size=7,
+ batch_size=2,
+ process_0_expected_batch_sizes=[2, 2],
+ process_1_expected_batch_sizes=[2, 2],
+ )
+
+
+def test_can_disable_even_batches():
+ accelerator = create_accelerator(even_batches=False)
+
+ verify_dataloader_batch_sizes(
+ accelerator,
+ dataset_size=3,
+ batch_size=1,
+ process_0_expected_batch_sizes=[1, 1],
+ process_1_expected_batch_sizes=[1],
+ )
+
+ verify_dataloader_batch_sizes(
+ accelerator,
+ dataset_size=7,
+ batch_size=2,
+ process_0_expected_batch_sizes=[2, 2],
+ process_1_expected_batch_sizes=[2, 1],
+ )
+
+
+def test_can_join_uneven_inputs():
+ accelerator = create_accelerator(even_batches=False)
+
+ model = torch.nn.Linear(1, 1)
+ ddp_model = accelerator.prepare(model)
+
+ dl = create_dataloader(accelerator, dataset_size=3, batch_size=1)
+
+ batch_idxs = []
+ with accelerator.join_uneven_inputs([ddp_model]):
+ for batch_idx, batch in enumerate(dl):
+ output = ddp_model(batch[0].float())
+ loss = output.sum()
+ loss.backward()
+ batch_idxs.append(batch_idx)
+
+ accelerator.wait_for_everyone()
+
+ if accelerator.process_index == 0:
+ assert batch_idxs == [0, 1]
+ elif accelerator.process_index == 1:
+ assert batch_idxs == [0]
+
+
+def test_join_raises_warning_for_non_ddp_distributed(accelerator):
+ with warnings.catch_warnings(record=True) as w:
+ with accelerator.join_uneven_inputs([Mock()]):
+ pass
+
+ assert issubclass(w[-1].category, UserWarning)
+ assert "only supported for multi-GPU" in str(w[-1].message)
+
+
+def test_join_can_override_even_batches():
+ default_even_batches = True
+ overridden_even_batches = False
+ accelerator = create_accelerator(even_batches=default_even_batches)
+ model = torch.nn.Linear(1, 1)
+ ddp_model = accelerator.prepare(model)
+ train_dl = create_dataloader(accelerator, dataset_size=3, batch_size=1)
+ valid_dl = create_dataloader(accelerator, dataset_size=3, batch_size=1)
+
+ with accelerator.join_uneven_inputs([ddp_model], even_batches=overridden_even_batches):
+ train_dl_overridden_value = train_dl.batch_sampler.even_batches
+ valid_dl_overridden_value = valid_dl.batch_sampler.even_batches
+
+ assert train_dl_overridden_value == overridden_even_batches
+ assert valid_dl_overridden_value == overridden_even_batches
+ assert train_dl.batch_sampler.even_batches == default_even_batches
+ assert valid_dl.batch_sampler.even_batches == default_even_batches
+
+
+def test_join_can_override_for_mixed_type_dataloaders():
+ default_even_batches = True
+ overridden_even_batches = False
+ accelerator = create_accelerator(even_batches=default_even_batches)
+ model = torch.nn.Linear(1, 1)
+ ddp_model = accelerator.prepare(model)
+ create_dataloader(accelerator, dataset_size=3, batch_size=1, iterable=True)
+ batch_dl = create_dataloader(accelerator, dataset_size=3, batch_size=1)
+
+ with warnings.catch_warnings():
+ warnings.filterwarnings("ignore")
+ try:
+ with accelerator.join_uneven_inputs([ddp_model], even_batches=overridden_even_batches):
+ batch_dl_overridden_value = batch_dl.batch_sampler.even_batches
+ except AttributeError:
+ # ensure attribute error is not raised when processing iterable dl
+ raise AssertionError
+
+ assert batch_dl_overridden_value == overridden_even_batches
+ assert batch_dl.batch_sampler.even_batches == default_even_batches
+
+
+def test_join_raises_warning_for_iterable_when_overriding_even_batches():
+ accelerator = create_accelerator()
+ model = torch.nn.Linear(1, 1)
+ ddp_model = accelerator.prepare(model)
+ create_dataloader(accelerator, dataset_size=3, batch_size=1, iterable=True)
+
+ with warnings.catch_warnings(record=True) as w:
+ with accelerator.join_uneven_inputs([ddp_model], even_batches=False):
+ pass
+
+ assert issubclass(w[-1].category, UserWarning)
+ assert "only supported for map-style datasets" in str(w[-1].message)
+
+
+def test_pickle_accelerator():
+ accelerator = create_accelerator()
+ data_loader = create_dataloader(accelerator, dataset_size=32, batch_size=4)
+ _ = accelerator.prepare(data_loader)
+ pickled_accelerator = pickle.dumps(accelerator)
+ unpickled_accelerator = pickle.loads(pickled_accelerator)
+ # TODO: Maybe this should be implemented as __eq__ for AcceleratorState?
+ assert accelerator.state.__dict__ == unpickled_accelerator.state.__dict__
+
+
+def test_data_loader(data_loader, accelerator):
+ # Prepare the DataLoader
+ data_loader = accelerator.prepare(data_loader)
+
+ all_examples = []
+ for i, batch in enumerate(data_loader):
+ index, _ = accelerator.gather_for_metrics((batch["index"], batch["label"]))
+ all_examples.extend(index.detach().cpu().numpy().tolist())
+
+ # Sort the examples
+ sorted_all_examples = sorted(all_examples)
+
+ # Check if all elements are present in the sorted list of iterated samples
+ assert len(set(sorted_all_examples)) == NUM_ELEMENTS, (
+ "Not all the dataset elements have been iterated in an epoch due to duplication of samples across processes."
+ )
+
+
+def test_stateful_dataloader(accelerator):
+ """
+ Tests that a stateful dataloader can be iterated over, saved after a few batches using `load_state_dict`, and then
+ resumed from the saved state.
+
+ The result should be the same as the rest of the data that iterated over after saving.
+ """
+ old_dataloader_config = accelerator.dataloader_config
+ try:
+ accelerator.dataloader_config = DataLoaderConfiguration(use_stateful_dataloader=True)
+ prepared_dl = create_dataloader(
+ accelerator, dataset_size=32 * accelerator.num_processes, batch_size=4, iterable=True, shuffle=True
+ )
+ untrained_batches = []
+ # Calculate what step that will be
+ total_batches = 32 * accelerator.num_processes // (4 * accelerator.num_processes)
+ last_batch_num = total_batches - 1
+ for step, batch in enumerate(prepared_dl):
+ # Step just before
+ if step == last_batch_num - 1:
+ state_dict = prepared_dl.state_dict()
+ if step >= last_batch_num:
+ # Otherwise grab the "unseen" batches
+ untrained_batches.append(batch)
+ not_skipped_batches = accelerator.gather(untrained_batches)
+ prepared_dl.load_state_dict(state_dict)
+ resumed_batches = []
+ for batch in prepared_dl:
+ resumed_batches.append(batch)
+ resumed_batches = accelerator.gather(resumed_batches)
+ for b1, b2 in zip(not_skipped_batches, resumed_batches):
+ for v1, v2 in zip(b1, b2):
+ assert torch.equal(v1, v2), f"Batch {b1} and {b2} are not equal"
+ finally:
+ accelerator.dataloader_config = old_dataloader_config
+
+
+def test_stateful_dataloader_save_state(accelerator):
+ """
+ Tests that a stateful dataloader can be iterated over, saved after a few batches using `Accelerator.save_state`,
+ and then resumed from the saved state.
+
+ The result should be the same as the rest of the data that iterated over after saving.
+ """
+ old_dataloader_config = accelerator.dataloader_config
+ try:
+ with tempfile.TemporaryDirectory() as tmpdir:
+ accelerator.dataloader_config = DataLoaderConfiguration(use_stateful_dataloader=True)
+ prepared_dl = create_dataloader(
+ accelerator, dataset_size=32 * accelerator.num_processes, batch_size=4, iterable=True, shuffle=True
+ )
+ untrained_batches = []
+ # Calculate what step that will be
+ total_batches = 32 * accelerator.num_processes // (4 * accelerator.num_processes)
+ last_batch_num = total_batches - 1
+ for step, batch in enumerate(prepared_dl):
+ # Step just before
+ if step == last_batch_num - 1:
+ accelerator.save_state(tmpdir)
+ if step >= last_batch_num:
+ # Otherwise grab the "unseen" batches
+ untrained_batches.append(batch)
+ not_skipped_batches = accelerator.gather(untrained_batches)
+ accelerator.load_state(tmpdir)
+ resumed_batches = []
+ for batch in prepared_dl:
+ resumed_batches.append(batch)
+ resumed_batches = accelerator.gather(resumed_batches)
+ for b1, b2 in zip(not_skipped_batches, resumed_batches):
+ for v1, v2 in zip(b1, b2):
+ assert torch.equal(v1, v2), f"Batch {b1} and {b2} are not equal"
+ finally:
+ accelerator.dataloader_config = old_dataloader_config
+
+
+def main():
+ accelerator = create_accelerator()
+ torch.manual_seed(accelerator.process_index)
+
+ accelerator.print("Test that even_batches variable ensures uniform batches across processes")
+ test_default_ensures_even_batch_sizes()
+
+ accelerator.print("Run tests with even_batches disabled")
+ test_can_disable_even_batches()
+
+ accelerator.print("Test joining uneven inputs")
+ test_can_join_uneven_inputs()
+
+ accelerator.print("Test overriding even_batches when joining uneven inputs")
+ test_join_can_override_even_batches()
+
+ accelerator.print("Test overriding even_batches for mixed dataloader types")
+ test_join_can_override_for_mixed_type_dataloaders()
+
+ accelerator.print("Test overriding even_batches raises a warning for iterable dataloaders")
+ test_join_raises_warning_for_iterable_when_overriding_even_batches()
+
+ accelerator.print("Test join with non DDP distributed raises warning")
+ original_state = accelerator.state.distributed_type
+ accelerator.state.distributed_type = DistributedType.FSDP
+ test_join_raises_warning_for_non_ddp_distributed(accelerator)
+ accelerator.state.distributed_type = original_state
+
+ accelerator.print("Test pickling an accelerator")
+ test_pickle_accelerator()
+
+ dataset = DummyDataset()
+
+ accelerator.print("Test DataLoader with shuffle=False")
+ loader = DataLoader(dataset, shuffle=False, batch_size=BATCH_SIZE, num_workers=NUM_WORKERS)
+ test_data_loader(loader, accelerator)
+
+ accelerator.print("Test DataLoader with shuffle=True")
+ loader = DataLoader(dataset, shuffle=True, batch_size=BATCH_SIZE, num_workers=NUM_WORKERS)
+ test_data_loader(loader, accelerator)
+
+ accelerator.print("Test DataLoader with batch_sampler")
+ sampler = BatchSampler(RandomSampler(dataset), batch_size=BATCH_SIZE, drop_last=False)
+ loader = DataLoader(dataset, batch_sampler=sampler, num_workers=NUM_WORKERS)
+ test_data_loader(loader, accelerator)
+
+ accelerator.print("Test DataLoader with sampler as an instance of `BatchSampler`")
+ sampler = BatchSampler(RandomSampler(dataset), batch_size=BATCH_SIZE, drop_last=False)
+ loader = DataLoader(dataset, sampler=sampler, batch_size=None, collate_fn=default_collate, num_workers=NUM_WORKERS)
+ test_data_loader(loader, accelerator)
+ test_stateful_dataloader(accelerator)
+ test_stateful_dataloader_save_state(accelerator)
+
+ accelerator.end_training()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_merge_weights.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_merge_weights.py
new file mode 100644
index 0000000000000000000000000000000000000000..f280c8fa17919367001389a8efcd78faaa041f0c
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_merge_weights.py
@@ -0,0 +1,158 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import gc
+import logging
+import shutil
+from pathlib import Path
+
+import torch
+from safetensors.torch import load_file
+from torch.distributed.fsdp.fully_sharded_data_parallel import ShardingStrategy, StateDictType
+from torch.utils.data import DataLoader
+
+from accelerate import Accelerator, FullyShardedDataParallelPlugin
+from accelerate.commands.merge import merge_command, merge_command_parser
+from accelerate.state import AcceleratorState
+from accelerate.test_utils import torch_device
+from accelerate.test_utils.training import RegressionDataset
+from accelerate.utils import merge_fsdp_weights, patch_environment, save_fsdp_model
+
+
+logging.basicConfig(level=logging.INFO)
+
+parser = merge_command_parser()
+
+
+class TinyModel(torch.nn.Module):
+ def __init__(self):
+ super().__init__()
+ self.linear1 = torch.nn.Linear(16, 16)
+ self.activation = torch.nn.ReLU()
+ self.linear2 = torch.nn.Linear(16, 16)
+ self.softmax = torch.nn.Softmax()
+
+ def forward(self, x):
+ return self.linear2(self.activation(self.linear1(x)))
+
+
+def setup():
+ if AcceleratorState._shared_state != {}:
+ AcceleratorState()._reset_state()
+ plugin = FullyShardedDataParallelPlugin(
+ sharding_strategy=ShardingStrategy.FULL_SHARD, state_dict_type=StateDictType.SHARDED_STATE_DICT
+ )
+ model = TinyModel()
+ with patch_environment(fsdp_auto_wrap_policy="SIZE_BASED_WRAP"):
+ plugin.set_auto_wrap_policy(model)
+ accelerator = Accelerator(fsdp_plugin=plugin)
+ model = accelerator.prepare(model)
+ return model, plugin, accelerator
+
+
+def mock_training(accelerator, model):
+ train_set = RegressionDataset(length=128, seed=42)
+ train_dl = DataLoader(train_set, batch_size=16, shuffle=False)
+ optimizer = torch.optim.SGD(model.parameters(), lr=0.1)
+
+ train_dl, model, optimizer = accelerator.prepare(train_dl, model, optimizer)
+ for _ in range(3):
+ for batch in train_dl:
+ model.zero_grad()
+ output = model(batch["x"])
+ loss = torch.nn.functional.mse_loss(output, batch["y"])
+ accelerator.backward(loss)
+ optimizer.step()
+ return model
+
+
+def check_weights(operation, state_1, state_2):
+ for weight_1, weight_2 in zip(state_1.values(), state_2.values()):
+ if operation == "same":
+ assert torch.allclose(weight_1, weight_2)
+ else:
+ assert not torch.allclose(weight_1, weight_2)
+
+
+def check_safetensors_weights(path, model):
+ safe_state_dict = load_file(path / "model.safetensors")
+ safe_loaded_model = TinyModel().to(torch_device)
+ check_weights("diff", model.state_dict(), safe_loaded_model.state_dict())
+ safe_loaded_model.load_state_dict(safe_state_dict)
+ check_weights("same", model.state_dict(), safe_loaded_model.state_dict())
+
+
+def check_pytorch_weights(path, model):
+ nonsafe_state_dict = torch.load(path / "pytorch_model.bin", weights_only=True)
+ nonsafe_loaded_model = TinyModel().to(torch_device)
+ check_weights("diff", model.state_dict(), nonsafe_loaded_model.state_dict())
+ nonsafe_loaded_model.load_state_dict(nonsafe_state_dict)
+ check_weights("same", model.state_dict(), nonsafe_loaded_model.state_dict())
+
+
+def test_merge_weights_safetensors(model, path):
+ # Should now be saved at `path/merged.safetensors`
+ merge_fsdp_weights(path / "pytorch_model_fsdp_0", path, safe_serialization=True)
+ check_safetensors_weights(path, model)
+
+
+def test_merge_weights_command_safetensors(model, path):
+ args = parser.parse_args([str(path / "pytorch_model_fsdp_0"), str(path)])
+ merge_command(args)
+ check_safetensors_weights(path, model)
+
+
+def test_merge_weights_pytorch(model, path):
+ # Should now be saved at `path/merged.bin`
+ merge_fsdp_weights(path / "pytorch_model_fsdp_0", path, safe_serialization=False)
+ check_pytorch_weights(path, model)
+
+
+def test_merge_weights_command_pytorch(model, path):
+ args = parser.parse_args([str(path / "pytorch_model_fsdp_0"), str(path), "--unsafe_serialization"])
+ merge_command(args)
+ check_pytorch_weights(path, model)
+
+
+if __name__ == "__main__":
+ # Note this test requires at least two accelerators!
+ model, plugin, accelerator = setup()
+ if accelerator.num_processes > 1:
+ try:
+ # Initial setup for things
+ out_path = Path("test_merge_weights_fsdp_weights")
+ if not out_path.exists():
+ out_path.mkdir(parents=True, exist_ok=True)
+
+ # Train briefly once weights aren't the baseline
+ model = mock_training(accelerator, model)
+ accelerator.wait_for_everyone()
+
+ gc.collect() # Needed for some lingering refs after training
+ save_fsdp_model(plugin, accelerator, model, out_path)
+ accelerator.wait_for_everyone()
+
+ # Finally we can test
+ test_merge_weights_safetensors(model, out_path)
+ test_merge_weights_command_safetensors(model, out_path)
+ test_merge_weights_pytorch(model, out_path)
+ test_merge_weights_command_pytorch(model, out_path)
+ except Exception:
+ raise
+ finally:
+ # Cleanup in case of any failures
+ if accelerator.is_main_process:
+ shutil.rmtree(out_path)
+ accelerator.wait_for_everyone()
+ accelerator.end_training()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_notebook.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_notebook.py
new file mode 100644
index 0000000000000000000000000000000000000000..267c11b50b22250e781f94e3643b8895cc6aeb02
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_notebook.py
@@ -0,0 +1,118 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Test file to ensure that in general certain situational setups for notebooks work.
+"""
+
+import os
+import time
+from multiprocessing import Queue
+
+from pytest import mark, raises
+from torch.distributed.elastic.multiprocessing.errors import ChildFailedError
+
+from accelerate import PartialState, notebook_launcher
+from accelerate.test_utils import require_bnb
+from accelerate.utils import is_bnb_available
+
+
+def basic_function():
+ # Just prints the PartialState
+ print(f"PartialState:\n{PartialState()}")
+
+
+def tough_nut_function(queue: Queue):
+ if queue.empty():
+ return
+ trial = queue.get()
+ if trial > 0:
+ queue.put(trial - 1)
+ raise RuntimeError("The nut hasn't cracked yet! Try again.")
+
+ print(f"PartialState:\n{PartialState()}")
+
+
+def bipolar_sleep_function(sleep_sec: int):
+ state = PartialState()
+ if state.process_index % 2 == 0:
+ raise RuntimeError("I'm an even process. I don't like to sleep.")
+ else:
+ time.sleep(sleep_sec)
+
+
+NUM_PROCESSES = int(os.environ.get("ACCELERATE_NUM_PROCESSES", 1))
+
+
+def test_can_initialize():
+ notebook_launcher(basic_function, (), num_processes=NUM_PROCESSES)
+
+
+@mark.skipif(NUM_PROCESSES < 2, reason="Need at least 2 processes to test static rendezvous backends")
+def test_static_rdzv_backend():
+ notebook_launcher(basic_function, (), num_processes=NUM_PROCESSES, rdzv_backend="static")
+
+
+@mark.skipif(NUM_PROCESSES < 2, reason="Need at least 2 processes to test c10d rendezvous backends")
+def test_c10d_rdzv_backend():
+ notebook_launcher(basic_function, (), num_processes=NUM_PROCESSES, rdzv_backend="c10d")
+
+
+@mark.skipif(NUM_PROCESSES < 2, reason="Need at least 2 processes to test fault tolerance")
+def test_fault_tolerant(max_restarts: int = 3):
+ queue = Queue()
+ queue.put(max_restarts)
+ notebook_launcher(tough_nut_function, (queue,), num_processes=NUM_PROCESSES, max_restarts=max_restarts)
+
+
+@mark.skipif(NUM_PROCESSES < 2, reason="Need at least 2 processes to test monitoring")
+def test_monitoring(monitor_interval: float = 0.01, sleep_sec: int = 100):
+ start_time = time.time()
+ with raises(ChildFailedError, match="I'm an even process. I don't like to sleep."):
+ notebook_launcher(
+ bipolar_sleep_function,
+ (sleep_sec,),
+ num_processes=NUM_PROCESSES,
+ monitor_interval=monitor_interval,
+ )
+ assert time.time() - start_time < sleep_sec, "Monitoring did not stop the process in time."
+
+
+@require_bnb
+def test_problematic_imports():
+ with raises(RuntimeError, match="Please keep these imports"):
+ import bitsandbytes as bnb # noqa: F401
+
+ notebook_launcher(basic_function, (), num_processes=NUM_PROCESSES)
+
+
+def main():
+ print("Test basic notebook can be ran")
+ test_can_initialize()
+ print("Test static rendezvous backend")
+ test_static_rdzv_backend()
+ print("Test c10d rendezvous backend")
+ test_c10d_rdzv_backend()
+ print("Test fault tolerant")
+ test_fault_tolerant()
+ print("Test monitoring")
+ test_monitoring()
+ if is_bnb_available():
+ print("Test problematic imports (bnb)")
+ test_problematic_imports()
+ if NUM_PROCESSES > 1:
+ PartialState().destroy_process_group()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_ops.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_ops.py
new file mode 100644
index 0000000000000000000000000000000000000000..1aa9b095e257bf63623b5127624b54c4a376c5ff
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_ops.py
@@ -0,0 +1,181 @@
+#!/usr/bin/env python
+
+# Copyright 2023 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import torch
+
+from accelerate import PartialState
+from accelerate.test_utils.testing import assert_exception
+from accelerate.utils.dataclasses import DistributedType
+from accelerate.utils.operations import (
+ DistributedOperationException,
+ broadcast,
+ copy_tensor_to_devices,
+ gather,
+ gather_object,
+ pad_across_processes,
+ reduce,
+)
+
+
+def create_tensor(state):
+ return (torch.arange(state.num_processes) + 1.0 + (state.num_processes * state.process_index)).to(state.device)
+
+
+def test_gather(state):
+ tensor = create_tensor(state)
+ gathered_tensor = gather(tensor)
+ assert gathered_tensor.tolist() == list(range(1, state.num_processes**2 + 1))
+
+
+def test_gather_object(state):
+ # Gather objects in TorchXLA is not supported.
+ if state.distributed_type == DistributedType.XLA:
+ return
+ obj = [state.process_index]
+ gathered_obj = gather_object(obj)
+ assert len(gathered_obj) == state.num_processes, f"{gathered_obj}, {len(gathered_obj)} != {state.num_processes}"
+ assert gathered_obj == list(range(state.num_processes)), f"{gathered_obj} != {list(range(state.num_processes))}"
+
+
+def test_gather_non_contiguous(state):
+ # Skip this test because the 'is_contiguous' function of XLA tensor always returns True.
+ if state.distributed_type == DistributedType.XLA:
+ return
+
+ # Create a non-contiguous tensor (enforce non-contiguity after device memory allocation)
+ tensor = torch.arange(12, device=state.device).view(4, 3).t()
+ assert not tensor.is_contiguous()
+ # Shouldn't error out
+ _ = gather(tensor)
+
+
+def test_broadcast(state):
+ tensor = create_tensor(state)
+ broadcasted_tensor = broadcast(tensor)
+ assert broadcasted_tensor.shape == torch.Size([state.num_processes])
+ assert broadcasted_tensor.tolist() == list(range(1, state.num_processes + 1))
+
+
+def test_pad_across_processes(state):
+ # We need to pad the tensor with one more element if we are the main process
+ # to ensure that we can pad
+ if state.is_main_process:
+ tensor = torch.arange(state.num_processes + 1).to(state.device)
+ else:
+ tensor = torch.arange(state.num_processes).to(state.device)
+ padded_tensor = pad_across_processes(tensor)
+ assert padded_tensor.shape == torch.Size([state.num_processes + 1])
+ if not state.is_main_process:
+ assert padded_tensor.tolist() == list(range(0, state.num_processes)) + [0]
+
+
+def test_reduce_sum(state):
+ # For now runs on only two processes
+ if state.num_processes != 2:
+ return
+ tensor = create_tensor(state)
+ reduced_tensor = reduce(tensor, "sum")
+ truth_tensor = torch.tensor([4.0, 6]).to(state.device)
+ assert torch.allclose(reduced_tensor, truth_tensor), f"{reduced_tensor} != {truth_tensor}"
+
+
+def test_reduce_mean(state):
+ # For now runs on only two processes
+ if state.num_processes != 2:
+ return
+ tensor = create_tensor(state)
+ reduced_tensor = reduce(tensor, "mean")
+ truth_tensor = torch.tensor([2.0, 3]).to(state.device)
+ assert torch.allclose(reduced_tensor, truth_tensor), f"{reduced_tensor} != {truth_tensor}"
+
+
+def test_op_checker(state):
+ # Must be in a distributed state, and gathering is currently not supported in TorchXLA.
+ if state.distributed_type in [DistributedType.NO, DistributedType.XLA]:
+ return
+ state.debug = True
+ # `pad_across_processes`
+ if state.process_index == 0:
+ data = {"tensor": torch.tensor([[0.0, 1, 2, 3, 4]]).to(state.device)}
+ else:
+ data = {"tensor": torch.tensor([[[0.0, 1, 2, 3, 4, 5]]]).to(state.device)}
+
+ with assert_exception(DistributedOperationException):
+ pad_across_processes(data, dim=0)
+
+ # `reduce`
+ if state.process_index == 0:
+ data = {"tensor": torch.tensor([[0.0, 1, 2, 3, 4]]).to(state.device)}
+ else:
+ data = {"tensor": torch.tensor([[[0.0, 1, 2, 3, 4], [5, 6, 7, 8, 9]]]).to(state.device)}
+
+ with assert_exception(DistributedOperationException):
+ reduce(data)
+
+ # `broadcast`
+ if state.process_index == 0:
+ data = {"tensor": torch.tensor([[0.0, 1, 2, 3, 4]]).to(state.device)}
+ else:
+ data = {"tensor": torch.tensor([[[0.0, 1, 2, 3, 4], [5, 6, 7, 8, 9]]]).to(state.device)}
+
+ with assert_exception(DistributedOperationException):
+ broadcast(data)
+
+ state.debug = False
+
+
+def test_copy_tensor_to_devices(state):
+ if state.distributed_type not in [DistributedType.MULTI_GPU, DistributedType.XLA]:
+ return
+ if state.is_main_process:
+ tensor = torch.tensor([1, 2, 3], dtype=torch.int).to(state.device)
+ else:
+ tensor = None
+ tensor = copy_tensor_to_devices(tensor)
+ assert torch.allclose(tensor, torch.tensor([1, 2, 3], dtype=torch.int, device=state.device))
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+def main():
+ state = PartialState()
+ state.print(f"State: {state}")
+ state.print("testing gather")
+ test_gather(state)
+ state.print("testing gather_object")
+ test_gather_object(state)
+ state.print("testing gather non-contiguous")
+ test_gather_non_contiguous(state)
+ state.print("testing broadcast")
+ test_broadcast(state)
+ state.print("testing pad_across_processes")
+ test_pad_across_processes(state)
+ state.print("testing reduce_sum")
+ test_reduce_sum(state)
+ state.print("testing reduce_mean")
+ test_reduce_mean(state)
+ state.print("testing op_checker")
+ test_op_checker(state)
+ state.print("testing sending tensors across devices")
+ test_copy_tensor_to_devices(state)
+ state.destroy_process_group()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_script.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_script.py
new file mode 100644
index 0000000000000000000000000000000000000000..a8e89df60cd421e39e025aa7cbc9ad01b27fe190
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_script.py
@@ -0,0 +1,947 @@
+#!/usr/bin/env python
+
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import contextlib
+import io
+import math
+import time
+from copy import deepcopy
+from pathlib import Path
+
+import numpy as np
+import torch
+from torch.utils.data import DataLoader, Dataset
+
+from accelerate import Accelerator
+from accelerate.data_loader import SeedableRandomSampler, prepare_data_loader
+from accelerate.state import AcceleratorState
+from accelerate.test_utils import RegressionDataset, RegressionModel, are_the_same_tensors
+from accelerate.utils import (
+ DataLoaderConfiguration,
+ DistributedType,
+ gather,
+ gather_object,
+ is_bf16_available,
+ is_cuda_available,
+ is_datasets_available,
+ is_fp16_available,
+ is_hpu_available,
+ is_ipex_available,
+ is_mps_available,
+ is_pytest_available,
+ set_seed,
+ synchronize_rng_states,
+)
+
+
+if is_hpu_available():
+ ATOL = 1e-3
+ RTOL = 1e-3
+else:
+ ATOL = 1e-6
+ RTOL = 1e-6
+
+
+def generate_baseline_dataloader(train_set, generator, batch_size, use_seedable_sampler=False):
+ "Creates a dataloader that can also use the `SeedableRandomSampler`"
+ if use_seedable_sampler:
+ # The SeedableRandomSampler is needed during distributed setups
+ # for full reproducibility across processes with the `DataLoader`
+ sampler = SeedableRandomSampler(
+ generator=generator,
+ data_source=train_set,
+ num_samples=len(train_set),
+ )
+ return DataLoader(train_set, batch_size=batch_size, sampler=sampler)
+ else:
+ return DataLoader(train_set, batch_size=batch_size, shuffle=True, generator=generator)
+
+
+def print_main(state):
+ print(f"Printing from the main process {state.process_index}")
+
+
+def print_local_main(state):
+ print(f"Printing from the local main process {state.local_process_index}")
+
+
+def print_last(state):
+ print(f"Printing from the last process {state.process_index}")
+
+
+def print_on(state, process_idx):
+ print(f"Printing from process {process_idx}: {state.process_index}")
+
+
+def process_execution_check():
+ accelerator = Accelerator()
+ num_processes = accelerator.num_processes
+ # Test main_process_first context manager
+ path = Path("check_main_process_first.txt")
+ with accelerator.main_process_first():
+ if accelerator.is_main_process:
+ time.sleep(0.1) # ensure main process takes longest
+ with open(path, "a+") as f:
+ f.write("Currently in the main process\n")
+ else:
+ with open(path, "a+") as f:
+ f.write("Now on another process\n")
+ accelerator.wait_for_everyone()
+
+ if accelerator.is_main_process:
+ with open(path) as f:
+ text = "".join(f.readlines())
+ try:
+ assert text.startswith("Currently in the main process\n"), "Main process was not first"
+ if num_processes > 1:
+ assert text.endswith("Now on another process\n"), "Main process was not first"
+ assert text.count("Now on another process\n") == accelerator.num_processes - 1, (
+ f"Only wrote to file {text.count('Now on another process') + 1} times, not {accelerator.num_processes}"
+ )
+ except AssertionError:
+ path.unlink()
+ raise
+
+ if accelerator.is_main_process and path.exists():
+ path.unlink()
+ accelerator.wait_for_everyone()
+ # Test the decorators
+ f = io.StringIO()
+ with contextlib.redirect_stdout(f):
+ accelerator.on_main_process(print_main)(accelerator.state)
+ result = f.getvalue().rstrip()
+ if accelerator.is_main_process:
+ assert result == "Printing from the main process 0", f"{result} != Printing from the main process 0"
+ else:
+ assert f.getvalue().rstrip() == "", f'{result} != ""'
+ f.truncate(0)
+ f.seek(0)
+
+ with contextlib.redirect_stdout(f):
+ accelerator.on_local_main_process(print_local_main)(accelerator.state)
+ if accelerator.is_local_main_process:
+ assert f.getvalue().rstrip() == "Printing from the local main process 0"
+ else:
+ assert f.getvalue().rstrip() == ""
+ f.truncate(0)
+ f.seek(0)
+
+ with contextlib.redirect_stdout(f):
+ accelerator.on_last_process(print_last)(accelerator.state)
+ if accelerator.is_last_process:
+ assert f.getvalue().rstrip() == f"Printing from the last process {accelerator.state.num_processes - 1}"
+ else:
+ assert f.getvalue().rstrip() == ""
+ f.truncate(0)
+ f.seek(0)
+
+ for process_idx in range(num_processes):
+ with contextlib.redirect_stdout(f):
+ accelerator.on_process(print_on, process_index=process_idx)(accelerator.state, process_idx)
+ if accelerator.process_index == process_idx:
+ assert f.getvalue().rstrip() == f"Printing from process {process_idx}: {accelerator.process_index}"
+ else:
+ assert f.getvalue().rstrip() == ""
+ f.truncate(0)
+ f.seek(0)
+
+
+def init_state_check():
+ # Test we can instantiate this twice in a row.
+ state = AcceleratorState()
+ if state.local_process_index == 0:
+ print("Testing, testing. 1, 2, 3.")
+ print(state)
+
+
+def rng_sync_check():
+ state = AcceleratorState()
+ synchronize_rng_states(["torch"])
+ assert are_the_same_tensors(torch.get_rng_state()), "RNG states improperly synchronized on CPU."
+ if state.distributed_type == DistributedType.MULTI_GPU:
+ synchronize_rng_states(["cuda"])
+ assert are_the_same_tensors(torch.cuda.get_rng_state()), "RNG states improperly synchronized on GPU."
+ elif state.distributed_type == DistributedType.MULTI_XPU:
+ synchronize_rng_states(["xpu"])
+ assert are_the_same_tensors(torch.xpu.get_rng_state()), "RNG states improperly synchronized on XPU."
+ generator = torch.Generator()
+ synchronize_rng_states(["generator"], generator=generator)
+ assert are_the_same_tensors(generator.get_state()), "RNG states improperly synchronized in generator."
+
+ if state.local_process_index == 0:
+ print("All rng are properly synched.")
+
+
+def dl_preparation_check():
+ state = AcceleratorState()
+ length = 32 * state.num_processes
+
+ dl = DataLoader(range(length), batch_size=8)
+ dl = prepare_data_loader(dl, state.device, state.num_processes, state.process_index, put_on_device=True)
+ result = []
+ for batch in dl:
+ result.append(gather(batch))
+ result = torch.cat(result)
+
+ assert torch.equal(result.cpu(), torch.arange(0, length).long()), "Wrong non-shuffled dataloader result."
+
+ dl = DataLoader(range(length), batch_size=8)
+ dl = prepare_data_loader(
+ dl,
+ state.device,
+ state.num_processes,
+ state.process_index,
+ put_on_device=True,
+ split_batches=True,
+ )
+ result = []
+ for batch in dl:
+ result.append(gather(batch))
+ result = torch.cat(result)
+ assert torch.equal(result.cpu(), torch.arange(0, length).long()), "Wrong non-shuffled dataloader result."
+
+ if state.process_index == 0:
+ print("Non-shuffled dataloader passing.")
+
+ dl = DataLoader(range(length), batch_size=8, shuffle=True)
+ dl = prepare_data_loader(dl, state.device, state.num_processes, state.process_index, put_on_device=True)
+ result = []
+ for batch in dl:
+ result.append(gather(batch))
+ result = torch.cat(result).tolist()
+ result.sort()
+ assert result == list(range(length)), "Wrong shuffled dataloader result."
+
+ dl = DataLoader(range(length), batch_size=8, shuffle=True)
+ dl = prepare_data_loader(
+ dl,
+ state.device,
+ state.num_processes,
+ state.process_index,
+ put_on_device=True,
+ split_batches=True,
+ )
+ result = []
+ for batch in dl:
+ result.append(gather(batch))
+ result = torch.cat(result).tolist()
+ result.sort()
+ assert result == list(range(length)), "Wrong shuffled dataloader result."
+
+ if state.local_process_index == 0:
+ print("Shuffled dataloader passing.")
+
+
+def central_dl_preparation_check():
+ state = AcceleratorState()
+ length = 32 * state.num_processes
+
+ dl = DataLoader(range(length), batch_size=8)
+ dl = prepare_data_loader(
+ dl, state.device, state.num_processes, state.process_index, put_on_device=True, dispatch_batches=True
+ )
+ result = []
+ for batch in dl:
+ result.append(gather(batch))
+ result = torch.cat(result)
+ assert torch.equal(result.cpu(), torch.arange(0, length).long()), "Wrong non-shuffled dataloader result."
+
+ dl = DataLoader(range(length), batch_size=8)
+ dl = prepare_data_loader(
+ dl,
+ state.device,
+ state.num_processes,
+ state.process_index,
+ put_on_device=True,
+ split_batches=True,
+ dispatch_batches=True,
+ )
+ result = []
+ for batch in dl:
+ result.append(gather(batch))
+ result = torch.cat(result)
+ assert torch.equal(result.cpu(), torch.arange(0, length).long()), "Wrong non-shuffled dataloader result."
+
+ if state.process_index == 0:
+ print("Non-shuffled central dataloader passing.")
+
+ dl = DataLoader(range(length), batch_size=8, shuffle=True)
+ dl = prepare_data_loader(
+ dl, state.device, state.num_processes, state.process_index, put_on_device=True, dispatch_batches=True
+ )
+ result = []
+ for batch in dl:
+ result.append(gather(batch))
+ result = torch.cat(result).tolist()
+ result.sort()
+ assert result == list(range(length)), "Wrong shuffled dataloader result."
+
+ dl = DataLoader(range(length), batch_size=8, shuffle=True)
+ dl = prepare_data_loader(
+ dl,
+ state.device,
+ state.num_processes,
+ state.process_index,
+ put_on_device=True,
+ split_batches=True,
+ dispatch_batches=True,
+ )
+ result = []
+ for batch in dl:
+ result.append(gather(batch))
+ result = torch.cat(result).tolist()
+ result.sort()
+ assert result == list(range(length)), "Wrong shuffled dataloader result."
+
+ if state.local_process_index == 0:
+ print("Shuffled central dataloader passing.")
+
+
+def custom_sampler_check():
+ state = AcceleratorState()
+
+ class CustomDataset(Dataset):
+ def __init__(self, data):
+ self.data = data
+
+ def __len__(self):
+ return len(self.data)
+
+ def __getitem__(self, index):
+ return self.data[index]
+
+ class CustomBatchSampler:
+ def __init__(self, dataset_length: int, batch_size: int, shuffle: bool = True):
+ self.batch_size = batch_size
+ self.data_index = np.arange(dataset_length)
+ self.shuffle = shuffle
+
+ def __iter__(self):
+ num_batches = len(self)
+ if self.shuffle:
+ index = np.random.permutation(self.data_index)
+ else:
+ index = self.data_index
+ output = np.array_split(index, num_batches)
+ yield from output
+
+ def __len__(self):
+ return math.ceil(len(self.data_index) / self.batch_size)
+
+ dataset = CustomDataset(range(32 * state.num_processes))
+ sampler = CustomBatchSampler(len(dataset), batch_size=8)
+ dl = DataLoader(dataset, batch_sampler=sampler)
+ dl = prepare_data_loader(dl, state.device, state.num_processes, state.process_index)
+ # We need just ensure that `dl.batch_sampler` (or `dl.batch_sampler.batch_sampler` is indeed the old batch sampler
+ if hasattr(dl.batch_sampler, "batch_sampler"):
+ assert isinstance(dl.batch_sampler.batch_sampler, CustomBatchSampler), (
+ "Custom sampler was changed after calling `prepare_data_loader`"
+ )
+ else:
+ assert isinstance(dl.batch_sampler, CustomBatchSampler), (
+ "Custom sampler was changed after calling `prepare_data_loader`"
+ )
+
+
+def check_seedable_sampler():
+ # Set seed
+ set_seed(42)
+ train_set = RegressionDataset(length=10, seed=42)
+ train_dl = DataLoader(train_set, batch_size=2, shuffle=True)
+
+ config = DataLoaderConfiguration(use_seedable_sampler=True)
+ accelerator = Accelerator(dataloader_config=config)
+ train_dl = accelerator.prepare(train_dl)
+ original_items = []
+ for _ in range(3):
+ for batch in train_dl:
+ original_items.append(batch["x"])
+ original_items = torch.cat(original_items)
+
+ # Set seed again and the epoch
+ set_seed(42)
+ train_dl.set_epoch(0)
+ new_items = []
+ for _ in range(3):
+ for batch in train_dl:
+ new_items.append(batch["x"])
+ new_items = torch.cat(new_items)
+ assert torch.allclose(original_items, new_items), "Did not obtain the same items with the same seed and epoch."
+
+
+def check_seedable_sampler_in_batch_sampler_shard():
+ set_seed(42)
+
+ config = DataLoaderConfiguration(use_seedable_sampler=True)
+ accelerator = Accelerator(dataloader_config=config)
+ assert accelerator.num_processes > 1, "This test requires more than one process."
+
+ dataloader = DataLoader(list(range(10)), batch_size=1, shuffle=True)
+ prepared_data_loader = prepare_data_loader(
+ dataloader=dataloader,
+ use_seedable_sampler=True,
+ )
+
+ target_sampler = prepared_data_loader.batch_sampler.batch_sampler.sampler
+ assert isinstance(target_sampler, SeedableRandomSampler), (
+ "Sampler in BatchSamplerShard is not SeedableRandomSampler."
+ )
+
+
+def check_seedable_sampler_with_data_seed():
+ # Set seed
+ set_seed(42)
+ data_seed = 42
+ train_set = RegressionDataset(length=10, seed=42)
+ train_dl = DataLoader(train_set, batch_size=2, shuffle=True)
+
+ config = DataLoaderConfiguration(use_seedable_sampler=True, data_seed=data_seed)
+ accelerator = Accelerator(dataloader_config=config)
+ prepared_dl = accelerator.prepare(train_dl)
+ original_items = []
+ for _ in range(3):
+ for batch in prepared_dl:
+ original_items.append(batch["x"])
+ original_items = torch.cat(original_items)
+
+ # Set new data seed
+ config.data_seed = 43
+ accelerator = Accelerator(dataloader_config=config)
+ prepared_dl = accelerator.prepare(train_dl)
+ new_items = []
+ for _ in range(3):
+ for batch in prepared_dl:
+ new_items.append(batch["x"])
+ new_items = torch.cat(new_items)
+ assert not torch.allclose(original_items, new_items), "Obtained the same items with different data seed."
+
+
+def mock_training(length, batch_size, generator, use_seedable_sampler=False):
+ set_seed(42)
+ generator.manual_seed(42)
+ train_set = RegressionDataset(length=length, seed=42)
+
+ train_dl = generate_baseline_dataloader(train_set, generator, batch_size, use_seedable_sampler)
+ model = RegressionModel()
+ optimizer = torch.optim.SGD(model.parameters(), lr=0.1)
+ for epoch in range(3):
+ for batch in train_dl:
+ model.zero_grad()
+ output = model(batch["x"])
+ loss = torch.nn.functional.mse_loss(output, batch["y"])
+ loss.backward()
+ optimizer.step()
+ return train_set, model
+
+
+def training_check(use_seedable_sampler=False):
+ state = AcceleratorState()
+ generator = torch.Generator()
+ batch_size = 8
+ length = batch_size * 4 * state.num_processes
+
+ train_set, old_model = mock_training(length, batch_size * state.num_processes, generator, use_seedable_sampler)
+ assert are_the_same_tensors(old_model.a), "Did not obtain the same model on both processes."
+ assert are_the_same_tensors(old_model.b), "Did not obtain the same model on both processes."
+
+ accelerator = Accelerator()
+ train_dl = generate_baseline_dataloader(train_set, generator, batch_size, use_seedable_sampler)
+ model = RegressionModel()
+ optimizer = torch.optim.SGD(model.parameters(), lr=0.1)
+
+ train_dl, model, optimizer = accelerator.prepare(train_dl, model, optimizer)
+ set_seed(42)
+ generator.manual_seed(42)
+ for _ in range(3):
+ for batch in train_dl:
+ model.zero_grad()
+ output = model(batch["x"])
+ loss = torch.nn.functional.mse_loss(output, batch["y"])
+ accelerator.backward(loss)
+ optimizer.step()
+
+ model = accelerator.unwrap_model(model).cpu()
+ torch.testing.assert_close(
+ old_model.a,
+ model.a,
+ atol=ATOL,
+ rtol=RTOL,
+ msg=lambda msg: f"Did not obtain the same model on CPU or distributed training.\n{msg}",
+ )
+ torch.testing.assert_close(
+ old_model.b,
+ model.b,
+ atol=ATOL,
+ rtol=RTOL,
+ msg=lambda msg: f"Did not obtain the same model on CPU or distributed training.\n{msg}",
+ )
+
+ accelerator.print("Training yielded the same results on one CPU or distributed setup with no batch split.")
+
+ dataloader_config = DataLoaderConfiguration(split_batches=True, use_seedable_sampler=use_seedable_sampler)
+ accelerator = Accelerator(dataloader_config=dataloader_config)
+ train_dl = generate_baseline_dataloader(
+ train_set, generator, batch_size * state.num_processes, use_seedable_sampler
+ )
+ model = RegressionModel()
+ optimizer = torch.optim.SGD(model.parameters(), lr=0.1)
+
+ train_dl, model, optimizer = accelerator.prepare(train_dl, model, optimizer)
+ set_seed(42)
+ generator.manual_seed(42)
+ for _ in range(3):
+ for batch in train_dl:
+ model.zero_grad()
+ output = model(batch["x"])
+ loss = torch.nn.functional.mse_loss(output, batch["y"])
+ accelerator.backward(loss)
+ optimizer.step()
+
+ model = accelerator.unwrap_model(model).cpu()
+ torch.testing.assert_close(
+ old_model.a,
+ model.a,
+ atol=ATOL,
+ rtol=RTOL,
+ msg=lambda msg: f"Did not obtain the same model on CPU or distributed training.\n{msg}",
+ )
+ torch.testing.assert_close(
+ old_model.b,
+ model.b,
+ atol=ATOL,
+ rtol=RTOL,
+ msg=lambda msg: f"Did not obtain the same model on CPU or distributed training.\n{msg}",
+ )
+
+ accelerator.print("Training yielded the same results on one CPU or distributed setup with batch split.")
+
+ # FP32 wrapper check
+ if is_cuda_available() or is_mps_available():
+ # Mostly a test that model.forward will have autocast when running unwrap_model(model, keep_fp32_wrapper=True)
+ print("Keep fp32 wrapper check.")
+ AcceleratorState._reset_state()
+ accelerator = Accelerator(mixed_precision="fp16")
+
+ model = torch.nn.Linear(2, 4)
+ model = accelerator.prepare(model)
+ model_with_fp32_wrapper = accelerator.unwrap_model(model, keep_fp32_wrapper=True)
+
+ # Run forward with fp16 as input.
+ # When the model is with mixed precision wrapper, no error will be raised.
+ input_tensor = torch.Tensor([1, 2]).to(dtype=torch.float16, device=accelerator.device)
+ output = model_with_fp32_wrapper(input_tensor)
+
+ # BF16 support
+ if is_bf16_available():
+ # Mostly a test that BF16 doesn't crash as the operation inside the model is not converted to BF16
+ print("BF16 training check.")
+ AcceleratorState._reset_state()
+ dataloader_config = DataLoaderConfiguration(use_seedable_sampler=use_seedable_sampler)
+ accelerator = Accelerator(mixed_precision="bf16", dataloader_config=dataloader_config)
+ train_dl = generate_baseline_dataloader(train_set, generator, batch_size, use_seedable_sampler)
+ model = RegressionModel()
+ optimizer = torch.optim.SGD(model.parameters(), lr=0.1)
+
+ train_dl, model, optimizer = accelerator.prepare(train_dl, model, optimizer)
+ set_seed(42)
+ generator.manual_seed(42)
+ for _ in range(3):
+ for batch in train_dl:
+ model.zero_grad()
+ output = model(batch["x"])
+ loss = torch.nn.functional.mse_loss(output, batch["y"])
+ accelerator.backward(loss)
+ optimizer.step()
+
+ model = accelerator.unwrap_model(model).cpu()
+ torch.testing.assert_close(
+ old_model.a,
+ model.a,
+ atol=ATOL,
+ rtol=RTOL,
+ msg=lambda msg: f"Did not obtain the same model on CPU or distributed training.\n{msg}",
+ )
+ torch.testing.assert_close(
+ old_model.b,
+ model.b,
+ atol=ATOL,
+ rtol=RTOL,
+ msg=lambda msg: f"Did not obtain the same model on CPU or distributed training.\n{msg}",
+ )
+
+ # FP16 support (HPU fp16 model seems to be off by 10% from the CPU, which is a lot of numerical error)
+ if is_fp16_available() and not is_hpu_available():
+ # Mostly a test that FP16 doesn't crash as the operation inside the model is not converted to FP16
+ print("FP16 training check.")
+ AcceleratorState._reset_state()
+ dataloader_config = DataLoaderConfiguration(use_seedable_sampler=use_seedable_sampler)
+ accelerator = Accelerator(mixed_precision="fp16", dataloader_config=dataloader_config)
+ train_dl = generate_baseline_dataloader(train_set, generator, batch_size, use_seedable_sampler)
+ model = RegressionModel()
+ optimizer = torch.optim.SGD(model.parameters(), lr=0.1)
+
+ train_dl, model, optimizer = accelerator.prepare(train_dl, model, optimizer)
+ set_seed(42)
+ generator.manual_seed(42)
+ for _ in range(3):
+ for batch in train_dl:
+ model.zero_grad()
+ output = model(batch["x"])
+ loss = torch.nn.functional.mse_loss(output, batch["y"])
+ accelerator.backward(loss)
+ optimizer.step()
+
+ model = accelerator.unwrap_model(model).cpu()
+ torch.testing.assert_close(
+ old_model.a,
+ model.a,
+ atol=ATOL,
+ rtol=RTOL,
+ msg=lambda msg: f"Did not obtain the same model on CPU or distributed training.\n{msg}",
+ )
+ torch.testing.assert_close(
+ old_model.b,
+ model.b,
+ atol=ATOL,
+ rtol=RTOL,
+ msg=lambda msg: f"Did not obtain the same model on CPU or distributed training.\n{msg}",
+ )
+
+ # IPEX CPU tests
+ if is_ipex_available():
+ print("ipex BF16 training check.")
+ AcceleratorState._reset_state()
+ dataloader_config = DataLoaderConfiguration(use_seedable_sampler=use_seedable_sampler)
+ accelerator = Accelerator(mixed_precision="bf16", cpu=True, dataloader_config=dataloader_config)
+ train_dl = generate_baseline_dataloader(train_set, generator, batch_size, use_seedable_sampler)
+ model = RegressionModel()
+ optimizer = torch.optim.SGD(model.parameters(), lr=0.1)
+
+ train_dl, model, optimizer = accelerator.prepare(train_dl, model, optimizer)
+ set_seed(42)
+ generator.manual_seed(42)
+ for _ in range(3):
+ for batch in train_dl:
+ model.zero_grad()
+ output = model(batch["x"])
+ loss = torch.nn.functional.mse_loss(output, batch["y"])
+ accelerator.backward(loss)
+ optimizer.step()
+
+ model = accelerator.unwrap_model(model).cpu()
+ torch.testing.assert_close(
+ old_model.a,
+ model.a,
+ atol=ATOL,
+ rtol=RTOL,
+ msg=lambda msg: f"Did not obtain the same model on CPU or distributed training.\n{msg}",
+ )
+ torch.testing.assert_close(
+ old_model.b,
+ model.b,
+ atol=ATOL,
+ rtol=RTOL,
+ msg=lambda msg: f"Did not obtain the same model on CPU or distributed training.\n{msg}",
+ )
+
+
+def test_split_between_processes_dataset(datasets_Dataset):
+ state = AcceleratorState()
+ data = datasets_Dataset.from_list([dict(k=v) for v in range(2 * state.num_processes)])
+ with state.split_between_processes(data, apply_padding=False) as results:
+ assert len(results) == 2, (
+ f"Each process did not have two items. Process index: {state.process_index}; Length: {len(results)}"
+ )
+
+ data = datasets_Dataset.from_list([dict(k=v) for v in range(2 * state.num_processes - 1)])
+ with state.split_between_processes(data, apply_padding=False) as results:
+ if state.is_last_process:
+ assert len(results) == 1, (
+ f"Last process did not receive a single item. Process index: {state.process_index}; Length: {len(results)}"
+ )
+ else:
+ assert len(results) == 2, (
+ f"One of the intermediate processes did not receive two items. Process index: {state.process_index}; Length: {len(results)}"
+ )
+ state.wait_for_everyone()
+
+ odd_data = datasets_Dataset.from_list([dict(k=v) for v in range(2 * state.num_processes - 1)])
+ even_data = datasets_Dataset.from_list([dict(k=v) for v in range(2 * state.num_processes)])
+
+ for data in [odd_data, even_data]:
+ expected_output = data["k"]
+
+ with state.split_between_processes(data, apply_padding=True) as results:
+ if state.num_processes == 1:
+ assert len(results) == len(data), (
+ f"Single process did not receive all items. Process index: {state.process_index}; Length: {len(results)}"
+ )
+ else:
+ assert len(results) == 2, (
+ f"Each process did not have two items. Process index: {state.process_index}; Length: {len(results)}"
+ )
+
+ results_per_process = []
+ for result in results:
+ results_per_process.append(result)
+
+ state.wait_for_everyone()
+
+ gathered_results = gather_object(results_per_process)
+ output = [r["k"] for r in gathered_results[: len(data)]]
+
+ assert expected_output == output, f"Gathered results is incorrect. Expected: {expected_output}; Got: {output}"
+
+
+def test_split_between_processes_list():
+ state = AcceleratorState()
+ data = list(range(0, 2 * state.num_processes))
+ with state.split_between_processes(data) as results:
+ assert len(results) == 2, (
+ f"Each process did not have two items. Process index: {state.process_index}; Length: {len(results)}"
+ )
+ state.wait_for_everyone()
+
+ even_data = list(range(0, (2 * state.num_processes)))
+ odd_data = list(range(0, (2 * state.num_processes) - 1))
+ for data in [odd_data, even_data]:
+ expected_output = data
+
+ with state.split_between_processes(data, apply_padding=True) as results:
+ num_samples_per_device = math.ceil(len(data) / state.num_processes)
+ # Test all processes gets the correct number of item(s)
+ assert len(results) == num_samples_per_device, (
+ f"Process {state.device} did not get the correct number of item(s). Process index: {state.process_index}; Length: {len(results)}"
+ )
+
+ results_per_process = []
+ for result in results:
+ results_per_process.append(result)
+
+ state.wait_for_everyone()
+
+ gathered_results = gather_object(results_per_process)
+ output = gathered_results[: len(data)]
+
+ assert expected_output == output, f"Gathered results is incorrect. Expected: {expected_output}; Got: {output}"
+
+
+def test_split_between_processes_nested_dict():
+ state = AcceleratorState()
+ a = [1, 2, 3, 4, 5, 6, 7, 8]
+ b = ["a", "b", "c", "d", "e", "f", "g", "h"]
+ c = torch.tensor([1, 2, 3, 4, 5, 6, 7, 8])
+ if state.num_processes in (1, 2, 4):
+ data = {"a": a, "b": b, "c": c}
+ data_copy = deepcopy(data)
+ with state.split_between_processes(data) as results:
+ if state.process_index == 0:
+ assert results["a"] == data_copy["a"][: 8 // state.num_processes]
+ elif state.num_processes == 2:
+ assert results["a"] == data_copy["a"][4:]
+ elif state.process_index == 3:
+ # We return a list each time
+ assert results["a"] == data_copy["a"][-2:], f"Expected: {data_copy['a'][-2]}, Actual: {results['a']}"
+ if state.process_index == 0:
+ assert results["b"] == data_copy["b"][: 8 // state.num_processes]
+ elif state.num_processes == 2:
+ assert results["b"] == data_copy["b"][4:]
+ elif state.process_index == 3:
+ assert results["b"] == data_copy["b"][-2:]
+ if state.process_index == 0:
+ assert torch.allclose(results["c"], data_copy["c"][: 8 // state.num_processes]), (
+ f"Did not obtain expected values on process 0, expected `{data['c'][: 8 // state.num_processes]}`, received: {results['c']}"
+ )
+ elif state.num_processes == 2:
+ assert torch.allclose(results["c"], data_copy["c"][4:]), (
+ f"Did not obtain expected values on process 2, expected `{data['c'][4:]}`, received: {results['c']}"
+ )
+ elif state.process_index == 3:
+ assert torch.allclose(results["c"], data_copy["c"][-2:]), (
+ f"Did not obtain expected values on process 4, expected `{data['c'][-2:]}`, received: {results['c']}"
+ )
+
+ state.wait_for_everyone()
+
+
+def test_split_between_processes_tensor():
+ state = AcceleratorState()
+ if state.num_processes > 1:
+ data = torch.tensor([[0, 1, 2, 3], [4, 5, 6, 7]]).to(state.device)
+ with state.split_between_processes(data) as results:
+ if state.process_index == 0:
+ expected = torch.tensor([[0, 1, 2, 3]]).to(state.device)
+ else:
+ expected = torch.tensor([[4, 5, 6, 7]]).to(state.device)
+ torch.testing.assert_close(results, expected)
+ state.wait_for_everyone()
+
+ even_data = torch.tensor([[i] for i in range(2 * state.num_processes)]).to(state.device)
+ odd_data = torch.tensor([[i] for i in range(2 * state.num_processes - 1)]).to(state.device)
+ for data in [even_data, odd_data]:
+ expected_output = [torch.tensor(i) for i in data.tolist()]
+
+ with state.split_between_processes(data, apply_padding=True) as results:
+ num_samples_per_device = math.ceil(len(data) / state.num_processes)
+ assert len(results) == num_samples_per_device, (
+ f"Process {state.device} did not get the correct number of item(s). Process index: {state.process_index}; Length: {len(results)}"
+ )
+ results_per_process = []
+ for result in results:
+ results_per_process.append(result.to("cpu"))
+
+ state.wait_for_everyone()
+
+ gathered_results = gather_object(results_per_process)
+ output = gathered_results[: len(data)]
+
+ assert expected_output == output, f"Gathered results is incorrect. Expected: {expected_output}; Got: {output}"
+
+
+def test_split_between_processes_evenly():
+ state = AcceleratorState()
+ if state.num_processes in (1, 2, 4, 8):
+ data = list(range(17))
+ num_samples_per_process = len(data) // state.num_processes
+ num_extras = len(data) % state.num_processes
+ with state.split_between_processes(data) as results:
+ if state.process_index < num_extras:
+ assert len(results) == num_samples_per_process + 1, (
+ f"Each Process should have even elements. Expected: {num_samples_per_process + 1}, Actual: {len(results)}"
+ )
+ else:
+ assert len(results) == num_samples_per_process, (
+ f"Each Process should have even elements. Expected: {num_samples_per_process}, Actual: {len(results)}"
+ )
+ state.wait_for_everyone()
+
+
+def test_trigger():
+ accelerator = Accelerator()
+ # should start with being false
+ assert accelerator.check_trigger() is False
+
+ # set a breakpoint on the main process
+ if accelerator.is_main_process:
+ accelerator.set_trigger()
+
+ # check it's been activated across all processes
+ # calls `all_reduce` and triggers a sync
+ assert accelerator.check_trigger() is True
+
+ # check it's been reset after the sync
+ assert accelerator.check_trigger() is False
+
+
+def test_reinstantiated_state():
+ import pytest
+
+ AcceleratorState._reset_state()
+ simple_model = torch.nn.Linear(1, 1)
+ # First define an accelerator
+ accelerator = Accelerator()
+ # Then call `reset_state`, breaking the state existing in the accelerator
+ AcceleratorState._reset_state()
+ # Now try and prepare a simple model, should raise the custom error early
+ with pytest.raises(AttributeError) as cm:
+ accelerator.prepare(simple_model)
+ assert "`AcceleratorState` object has no attribute" in str(cm.value.args[0])
+ assert "This happens if `AcceleratorState._reset_state()`" in str(cm.value.args[0])
+
+
+def main():
+ accelerator = Accelerator()
+ state = accelerator.state
+ if state.local_process_index == 0:
+ print("**Initialization**")
+ init_state_check()
+ state.wait_for_everyone()
+
+ if state.distributed_type == DistributedType.MULTI_GPU:
+ num_processes_per_node = torch.cuda.device_count()
+ else:
+ num_processes_per_node = state.num_processes
+
+ # We only run this test on non-multinode
+ if num_processes_per_node == state.num_processes:
+ if state.process_index == 0:
+ print("\n**Test process execution**")
+ process_execution_check()
+
+ if state.process_index == 0:
+ print("\n**Test split between processes as a list**")
+ test_split_between_processes_list()
+
+ if state.process_index == 0:
+ print("\n**Test split between processes as a dict**")
+ test_split_between_processes_nested_dict()
+
+ if state.process_index == 0:
+ print("\n**Test split between processes as a tensor**")
+ test_split_between_processes_tensor()
+
+ if state.process_index == 0:
+ print("\n**Test split between processes evenly**")
+ test_split_between_processes_evenly()
+
+ if state.process_index == 0:
+ print("\n**Test split between processes as a datasets.Dataset**")
+ if is_datasets_available():
+ from datasets import Dataset as datasets_Dataset
+
+ test_split_between_processes_dataset(datasets_Dataset)
+ else:
+ print("Skipped because Hugging Face datasets is not available")
+
+ if state.local_process_index == 0:
+ print("\n**Test random number generator synchronization**")
+ rng_sync_check()
+
+ if state.local_process_index == 0:
+ print("\n**DataLoader integration test**")
+ dl_preparation_check()
+ if state.distributed_type != DistributedType.XLA:
+ central_dl_preparation_check()
+ custom_sampler_check()
+ check_seedable_sampler()
+ check_seedable_sampler_with_data_seed()
+
+ if state.num_processes > 1:
+ check_seedable_sampler_in_batch_sampler_shard()
+
+ # Trainings are not exactly the same in DeepSpeed and CPU mode
+ if state.distributed_type == DistributedType.DEEPSPEED:
+ return
+
+ if state.local_process_index == 0:
+ print("\n**Training integration test**")
+ training_check(use_seedable_sampler=False)
+ training_check(use_seedable_sampler=True)
+
+ if state.local_process_index == 0:
+ print("\n**Breakpoint trigger test**")
+ test_trigger()
+
+ if is_pytest_available():
+ if state.local_process_index == 0:
+ print("\n**Test reinstantiated state**")
+ test_reinstantiated_state()
+
+ state.destroy_process_group()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_sync.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_sync.py
new file mode 100644
index 0000000000000000000000000000000000000000..44e1ecc1d59c5691f284282fb8cd2259c8a70658
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/scripts/test_sync.py
@@ -0,0 +1,410 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from copy import deepcopy
+
+import torch
+import torch.nn.functional as F
+from torch.optim import AdamW
+from torch.optim.lr_scheduler import LambdaLR
+from torch.utils.data import DataLoader
+
+from accelerate.accelerator import Accelerator, DataLoaderConfiguration, GradientAccumulationPlugin
+from accelerate.state import GradientState
+from accelerate.test_utils import RegressionDataset, RegressionModel
+from accelerate.utils import DistributedType, set_seed
+
+
+def check_model_parameters(model_a, model_b, did_step, iteration, **kwargs):
+ for param, grad_param in zip(model_a.parameters(), model_b.parameters()):
+ if not param.requires_grad:
+ continue
+ if not did_step:
+ # Grads should not be in sync
+ assert torch.allclose(param.grad, grad_param.grad, **kwargs) is False, (
+ f"Gradients in sync when they should not be at iteration {iteration}:\nmodel_a grad ({param.grad}) == model_b grad ({grad_param.grad})"
+ )
+ else:
+ # Grads should be in sync
+ assert torch.allclose(param.grad, grad_param.grad, **kwargs) is True, (
+ f"Gradients not in sync when they should be at iteration {iteration}:\nmodel_a grad ({param.grad}) != model_b grad ({grad_param.grad})"
+ )
+
+
+def step_model(model, input, target, accelerator, do_backward=True):
+ model.train()
+ output = model(input)
+ loss = F.mse_loss(output, target.to(output.device))
+ if not do_backward:
+ loss /= accelerator.gradient_accumulation_steps
+ loss.backward()
+ else:
+ accelerator.backward(loss)
+
+
+def get_training_setup(accelerator, sched=False):
+ "Returns everything needed to perform basic training"
+ set_seed(42)
+ model = RegressionModel()
+ ddp_model = deepcopy(model)
+ dset = RegressionDataset(length=80)
+ dataloader = DataLoader(dset, batch_size=16)
+ model.to(accelerator.device)
+ if sched:
+ opt = AdamW(params=model.parameters(), lr=1e-3)
+ ddp_opt = AdamW(params=ddp_model.parameters(), lr=1e-3)
+ sched = LambdaLR(opt, lr_lambda=lambda epoch: epoch**0.65)
+ ddp_sched = LambdaLR(ddp_opt, lr_lambda=lambda epoch: epoch**0.65)
+ # Make a copy of `model`
+ if sched:
+ ddp_model, ddp_opt, ddp_sched, dataloader = accelerator.prepare(ddp_model, ddp_opt, ddp_sched, dataloader)
+ else:
+ ddp_model, dataloader = accelerator.prepare(ddp_model, dataloader)
+ if sched:
+ return (model, opt, sched, dataloader, ddp_model, ddp_opt, ddp_sched)
+ return model, ddp_model, dataloader
+
+
+def test_noop_sync(accelerator):
+ # Test when on a single CPU or GPU that the context manager does nothing
+ model, ddp_model, dataloader = get_training_setup(accelerator)
+ # Use a single batch
+ ddp_input, ddp_target = next(iter(dataloader)).values()
+ for iteration in range(3):
+ # Gather the distributed inputs and targs for the base model
+ input, target = accelerator.gather((ddp_input, ddp_target))
+ input, target = input.to(accelerator.device), target.to(accelerator.device)
+ # Perform our initial ground truth step in non "DDP"
+ step_model(model, input, target, accelerator)
+ # Do "gradient accumulation" (noop)
+ if iteration % 2 == 0:
+ # Accumulate grads locally
+ with accelerator.no_sync(ddp_model):
+ step_model(ddp_model, ddp_input, ddp_target, accelerator)
+ else:
+ # Sync grads
+ step_model(ddp_model, ddp_input, ddp_target, accelerator)
+
+ # Since `no_sync` is a noop, `ddp_model` and `model` grads should always be in sync
+ check_model_parameters(model, ddp_model, True, iteration)
+ for param, ddp_param in zip(model.parameters(), ddp_model.parameters()):
+ if not param.requires_grad:
+ continue
+ assert torch.allclose(param.grad, ddp_param.grad), (
+ f"Gradients not in sync when they should be:\nModel grad ({param.grad}) != DDP grad ({ddp_param.grad})"
+ )
+
+ # Shuffle ddp_input on each iteration
+ torch.manual_seed(1337 + iteration)
+ ddp_input = ddp_input[torch.randperm(len(ddp_input))]
+
+
+def test_distributed_sync(accelerator):
+ # Test on distributed setup that context manager behaves properly
+ model, ddp_model, dataloader = get_training_setup(accelerator)
+ # Use a single batch
+ ddp_input, ddp_target = next(iter(dataloader)).values()
+ for iteration in range(3):
+ # Gather the distributed inputs and targs for the base model
+ input, target = accelerator.gather((ddp_input, ddp_target))
+ input, target = input.to(accelerator.device), target.to(accelerator.device)
+ # Perform our initial ground truth step in non "DDP"
+ step_model(model, input, target, accelerator)
+ # Do "gradient accumulation" (noop)
+ if iteration % 2 == 0:
+ # Accumulate grads locally
+ with accelerator.no_sync(ddp_model):
+ step_model(ddp_model, ddp_input, ddp_target, accelerator)
+ else:
+ # Sync grads
+ step_model(ddp_model, ddp_input, ddp_target, accelerator)
+
+ # DDP model and model should only be in sync when not (iteration % 2 == 0)
+ for param, ddp_param in zip(model.parameters(), ddp_model.parameters()):
+ if not param.requires_grad:
+ continue
+ if iteration % 2 == 0:
+ # Grads should not be in sync
+ assert torch.allclose(param.grad, ddp_param.grad) is False, (
+ f"Gradients in sync when they should not be:\nModel grad ({param.grad}) == DDP grad ({ddp_param.grad})"
+ )
+ else:
+ # Grads should be in sync
+ assert torch.allclose(param.grad, ddp_param.grad) is True, (
+ f"Gradients not in sync when they should be:\nModel grad ({param.grad}) != DDP grad ({ddp_param.grad})"
+ )
+
+ # Shuffle ddp_input on each iteration
+ torch.manual_seed(1337 + iteration)
+ ddp_input = ddp_input[torch.randperm(len(ddp_input))]
+
+
+def test_distributed_sync_multiple_fwd(accelerator):
+ # Test on distributed setup that context manager behaves properly when used with multiple forwards followed by multiple backwards
+ model, ddp_model, dataloader = get_training_setup(accelerator)
+ # Do multiple forwards
+ losses = []
+ num_iterations = 3
+ for iteration in range(num_iterations):
+ ddp_input, ddp_target = next(iter(dataloader)).values()
+
+ # Gather the distributed inputs and targs for the base model
+ input, target = accelerator.gather((ddp_input, ddp_target))
+ input, target = input.to(accelerator.device), target.to(accelerator.device)
+
+ # Perform our initial ground truth step in non "DDP"
+ step_model(model, input, target, accelerator)
+
+ # Accumulate grads locally
+ with accelerator.no_sync(ddp_model):
+ ddp_output = ddp_model(ddp_input)
+ loss = F.mse_loss(ddp_output, ddp_target.to(ddp_output.device))
+ losses.append(loss)
+
+ # Do multiple backwards and sync only at the last backward
+ for iteration in range(num_iterations):
+ loss = losses[iteration]
+
+ if iteration < num_iterations - 1:
+ # Accumulate grads locally
+ accelerator.backward(loss)
+
+ # DDP model and model should only be in sync after last backward
+ for param, ddp_param in zip(model.parameters(), ddp_model.parameters()):
+ if not param.requires_grad:
+ continue
+ # Grads should not be in sync
+ assert torch.allclose(param.grad, ddp_param.grad) is False, (
+ f"Gradients in sync when they should not be:\nModel grad ({param.grad}) == DDP grad ({ddp_param.grad})"
+ )
+
+ else:
+ # Sync grads if last backward
+ with accelerator.trigger_sync_in_backward(ddp_model):
+ accelerator.backward(loss)
+
+ # DDP model and model should only be in sync after last backward
+ for param, ddp_param in zip(model.parameters(), ddp_model.parameters()):
+ if not param.requires_grad:
+ continue
+ # Grads should be in sync
+ assert torch.allclose(param.grad, ddp_param.grad) is True, (
+ f"Gradients not in sync when they should be:\nModel grad ({param.grad}) != DDP grad ({ddp_param.grad})"
+ )
+
+
+def test_gradient_accumulation(split_batches=False, dispatch_batches=False, sync_each_batch=False):
+ gradient_accumulation_plugin = GradientAccumulationPlugin(num_steps=2, sync_each_batch=sync_each_batch)
+ dataloader_config = DataLoaderConfiguration(split_batches=split_batches, dispatch_batches=dispatch_batches)
+ accelerator = Accelerator(
+ dataloader_config=dataloader_config,
+ gradient_accumulation_plugin=gradient_accumulation_plugin,
+ )
+ # Test that context manager behaves properly
+ model, ddp_model, dataloader = get_training_setup(accelerator)
+ for iteration, batch in enumerate(dataloader):
+ ddp_input, ddp_target = batch.values()
+ # Gather the distributed inputs and targs for the base model
+ input, target = accelerator.gather((ddp_input, ddp_target))
+ input, target = input.to(accelerator.device), target.to(accelerator.device)
+ # Perform our initial ground truth step in non "DDP"
+ step_model(model, input, target, accelerator, False)
+ # Do "gradient accumulation" (noop)
+ with accelerator.accumulate(ddp_model):
+ step_model(ddp_model, ddp_input, ddp_target, accelerator)
+
+ # DDP model and model should only be in sync when not (iteration % 2 == 0)
+ for param, ddp_param in zip(model.parameters(), ddp_model.parameters()):
+ if not param.requires_grad:
+ continue
+ if ((iteration + 1) % 2 == 0) or (iteration == len(dataloader) - 1) or sync_each_batch:
+ # Grads should be in sync
+ assert torch.allclose(param.grad, ddp_param.grad) is True, (
+ f"Gradients not in sync when they should be at iteration {iteration}:\nModel grad ({param.grad}) != DDP grad ({ddp_param.grad})"
+ )
+ else:
+ # Grads should not be in sync
+ assert torch.allclose(param.grad, ddp_param.grad) is False, (
+ f"Gradients in sync when they should not be at iteration {iteration}:\nModel grad ({param.grad}) == DDP grad ({ddp_param.grad})"
+ )
+
+ # Shuffle ddp_input on each iteration
+ torch.manual_seed(1337 + iteration)
+ ddp_input = ddp_input[torch.randperm(len(ddp_input))]
+ GradientState._reset_state()
+
+
+def test_gradient_accumulation_with_opt_and_scheduler(
+ split_batches=False, dispatch_batches=False, sync_each_batch=False
+):
+ gradient_accumulation_plugin = GradientAccumulationPlugin(num_steps=2, sync_each_batch=sync_each_batch)
+ dataloader_config = DataLoaderConfiguration(split_batches=split_batches, dispatch_batches=dispatch_batches)
+ accelerator = Accelerator(
+ dataloader_config=dataloader_config,
+ gradient_accumulation_plugin=gradient_accumulation_plugin,
+ )
+ # Test that context manager behaves properly
+ model, opt, sched, dataloader, ddp_model, ddp_opt, ddp_sched = get_training_setup(accelerator, True)
+ for iteration, batch in enumerate(dataloader):
+ ddp_input, ddp_target = batch.values()
+ # Gather the distributed inputs and targs for the base model
+ input, target = accelerator.gather((ddp_input, ddp_target))
+ input, target = input.to(accelerator.device), target.to(accelerator.device)
+ # Perform our initial ground truth step in non "DDP"
+ model.train()
+ ddp_model.train()
+ step_model(model, input, target, accelerator, False)
+ opt.step()
+
+ if ((iteration + 1) % 2 == 0) or ((iteration + 1) == len(dataloader)):
+ if split_batches:
+ sched.step()
+ else:
+ for _ in range(accelerator.num_processes):
+ sched.step()
+
+ # Perform gradient accumulation under wrapper
+ with accelerator.accumulate(ddp_model):
+ step_model(ddp_model, ddp_input, ddp_target, accelerator)
+ ddp_opt.step()
+ ddp_sched.step()
+
+ # Learning rates should be the same
+ assert opt.param_groups[0]["lr"] == ddp_opt.param_groups[0]["lr"], (
+ f"Learning rates found in each optimizer did not align\nopt: {opt.param_groups[0]['lr']}\nDDP opt: {ddp_opt.param_groups[0]['lr']}\n"
+ )
+ did_step = (((iteration + 1) % 2) == 0) or ((iteration + 1) == len(dataloader))
+ if accelerator.num_processes > 1:
+ check_model_parameters(
+ model,
+ ddp_model,
+ did_step or sync_each_batch, # syncs at each grad_accum interval of if sync_each_batch==True
+ iteration,
+ rtol=1e-3, # needs a relative tolerance due to roundoff errors
+ )
+
+ if did_step:
+ opt.zero_grad() # flush gradients every accum step
+ ddp_opt.zero_grad()
+
+ # Shuffle ddp_input on each iteration
+ torch.manual_seed(1337 + iteration)
+ GradientState._reset_state()
+
+
+def test_dataloader_break():
+ accelerator = Accelerator()
+ first_dset = RegressionDataset(length=80)
+ first_dataloader = DataLoader(first_dset, batch_size=16)
+ second_dset = RegressionDataset(length=96)
+ second_dataloader = DataLoader(second_dset, batch_size=16)
+ first_dataloader, second_dataloader = accelerator.prepare(first_dataloader, second_dataloader)
+
+ assert accelerator.gradient_state.active_dataloader is None
+ for iteration, _ in enumerate(first_dataloader):
+ assert id(accelerator.gradient_state.active_dataloader) == id(first_dataloader)
+ if iteration < len(first_dataloader) - 1:
+ assert not accelerator.gradient_state.end_of_dataloader
+ if iteration == 1:
+ for batch_num, _ in enumerate(second_dataloader):
+ assert id(accelerator.gradient_state.active_dataloader) == id(second_dataloader)
+ if batch_num < len(second_dataloader) - 1:
+ assert not accelerator.gradient_state.end_of_dataloader
+ else:
+ assert accelerator.gradient_state.end_of_dataloader
+ else:
+ assert accelerator.gradient_state.end_of_dataloader
+ assert accelerator.gradient_state.active_dataloader is None
+
+
+def main():
+ accelerator = Accelerator()
+ state = accelerator.state
+ if state.local_process_index == 0:
+ print("**Test `accumulate` gradient accumulation with dataloader break**")
+ if state.distributed_type != DistributedType.XLA:
+ test_dataloader_break()
+ if state.distributed_type == DistributedType.NO:
+ if state.local_process_index == 0:
+ print("**Test NOOP `no_sync` context manager**")
+ test_noop_sync(accelerator)
+ if state.distributed_type in (
+ DistributedType.MULTI_GPU,
+ DistributedType.MULTI_NPU,
+ DistributedType.MULTI_MLU,
+ DistributedType.MULTI_SDAA,
+ DistributedType.MULTI_MUSA,
+ DistributedType.MULTI_CPU,
+ DistributedType.MULTI_HPU,
+ ):
+ if state.local_process_index == 0:
+ print("**Test Distributed `no_sync` context manager**")
+ test_distributed_sync(accelerator)
+ if state.local_process_index == 0:
+ print("**Test Distributed `no_sync` context manager with multiple forwards**")
+ test_distributed_sync_multiple_fwd(accelerator)
+ if state.distributed_type in (
+ DistributedType.MULTI_GPU,
+ DistributedType.MULTI_NPU,
+ DistributedType.MULTI_MLU,
+ DistributedType.MULTI_SDAA,
+ DistributedType.MULTI_MUSA,
+ DistributedType.MULTI_HPU,
+ ):
+ for split_batch in [True, False]:
+ for dispatch_batches in [True, False]:
+ for sync_each_batch in [True, False]:
+ if state.local_process_index == 0:
+ print(
+ "**Test `accumulate` gradient accumulation, ",
+ f"`split_batches={split_batch}` and `dispatch_batches={dispatch_batches}` and `sync_each_batch={sync_each_batch}`**",
+ )
+ test_gradient_accumulation(split_batch, dispatch_batches, sync_each_batch)
+
+ # Currently will break on torch 2.0 +, need to investigate why
+ if state.local_process_index == 0:
+ print(
+ "**Test `accumulate` gradient accumulation with optimizer and scheduler, ",
+ "`split_batches=False`, `dispatch_batches=False`, `sync_each_batch=False`**",
+ )
+ test_gradient_accumulation_with_opt_and_scheduler()
+ if state.distributed_type in (
+ DistributedType.MULTI_GPU,
+ DistributedType.MULTI_NPU,
+ DistributedType.MULTI_MLU,
+ DistributedType.MULTI_SDAA,
+ DistributedType.MULTI_MUSA,
+ DistributedType.MULTI_HPU,
+ ):
+ for split_batch in [True, False]:
+ for dispatch_batches in [True, False]:
+ for sync_each_batch in [True, False]:
+ if not split_batch and not dispatch_batches and not sync_each_batch:
+ continue
+ if state.local_process_index == 0:
+ print(
+ "**Test `accumulate` gradient accumulation with optimizer and scheduler, ",
+ f"`split_batches={split_batch}` and `dispatch_batches={dispatch_batches}` and `sync_each_batch={sync_each_batch}`**",
+ )
+ test_gradient_accumulation_with_opt_and_scheduler(split_batch, dispatch_batches, sync_each_batch)
+ state.destroy_process_group()
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/testing.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/testing.py
new file mode 100644
index 0000000000000000000000000000000000000000..92b229ff8e4c67266ca5029045a07967c2d4d84b
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/testing.py
@@ -0,0 +1,881 @@
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import asyncio
+import inspect
+import io
+import os
+import re
+import shutil
+import subprocess
+import sys
+import tempfile
+import unittest
+from contextlib import contextmanager
+from functools import partial
+from pathlib import Path
+from typing import Optional, Union
+from unittest import mock
+
+import torch
+
+import accelerate
+
+from ..state import AcceleratorState
+from ..utils import (
+ check_cuda_fp8_capability,
+ compare_versions,
+ gather,
+ is_aim_available,
+ is_bnb_available,
+ is_clearml_available,
+ is_comet_ml_available,
+ is_cuda_available,
+ is_datasets_available,
+ is_deepspeed_available,
+ is_dvclive_available,
+ is_fp8_available,
+ is_fp16_available,
+ is_habana_gaudi1,
+ is_hpu_available,
+ is_import_timer_available,
+ is_matplotlib_available,
+ is_mlflow_available,
+ is_mlu_available,
+ is_mps_available,
+ is_musa_available,
+ is_npu_available,
+ is_pandas_available,
+ is_pippy_available,
+ is_pytest_available,
+ is_schedulefree_available,
+ is_sdaa_available,
+ is_swanlab_available,
+ is_tensorboard_available,
+ is_timm_available,
+ is_torch_version,
+ is_torch_xla_available,
+ is_torchao_available,
+ is_torchdata_stateful_dataloader_available,
+ is_torchvision_available,
+ is_trackio_available,
+ is_transformer_engine_available,
+ is_transformer_engine_mxfp8_available,
+ is_transformers_available,
+ is_triton_available,
+ is_wandb_available,
+ is_xpu_available,
+ str_to_bool,
+)
+
+
+def get_backend():
+ if is_torch_xla_available():
+ return "xla", torch.cuda.device_count(), torch.cuda.memory_allocated
+ elif is_cuda_available():
+ return "cuda", torch.cuda.device_count(), torch.cuda.memory_allocated
+ elif is_mps_available(min_version="2.0"):
+ return "mps", 1, torch.mps.current_allocated_memory
+ elif is_mps_available():
+ return "mps", 1, lambda: 0
+ elif is_mlu_available():
+ return "mlu", torch.mlu.device_count(), torch.mlu.memory_allocated
+ elif is_sdaa_available():
+ return "sdaa", torch.sdaa.device_count(), torch.sdaa.memory_allocated
+ elif is_musa_available():
+ return "musa", torch.musa.device_count(), torch.musa.memory_allocated
+ elif is_npu_available():
+ return "npu", torch.npu.device_count(), torch.npu.memory_allocated
+ elif is_xpu_available():
+ return "xpu", torch.xpu.device_count(), torch.xpu.memory_allocated
+ elif is_hpu_available():
+ return "hpu", torch.hpu.device_count(), torch.hpu.memory_allocated
+ else:
+ return "cpu", 1, lambda: 0
+
+
+torch_device, device_count, memory_allocated_func = get_backend()
+
+
+def get_launch_command(**kwargs) -> list:
+ """
+ Wraps around `kwargs` to help simplify launching from `subprocess`.
+
+ Example:
+ ```python
+ # returns ['accelerate', 'launch', '--num_processes=2', '--device_count=2']
+ get_launch_command(num_processes=2, device_count=2)
+ ```
+ """
+ command = ["accelerate", "launch"]
+ for k, v in kwargs.items():
+ if isinstance(v, bool) and v:
+ command.append(f"--{k}")
+ elif v is not None:
+ command.append(f"--{k}={v}")
+ return command
+
+
+DEFAULT_LAUNCH_COMMAND = get_launch_command(num_processes=device_count, monitor_interval=0.1)
+
+
+def parse_flag_from_env(key, default=False):
+ try:
+ value = os.environ[key]
+ except KeyError:
+ # KEY isn't set, default to `default`.
+ _value = default
+ else:
+ # KEY is set, convert it to True or False.
+ try:
+ _value = str_to_bool(value)
+ except ValueError:
+ # More values are supported, but let's keep the message simple.
+ raise ValueError(f"If set, {key} must be yes or no.")
+ return _value
+
+
+_run_slow_tests = parse_flag_from_env("RUN_SLOW", default=False)
+
+
+def skip(test_case):
+ "Decorator that skips a test unconditionally"
+ return unittest.skip("Test was skipped")(test_case)
+
+
+def slow(test_case):
+ """
+ Decorator marking a test as slow. Slow tests are skipped by default. Set the RUN_SLOW environment variable to a
+ truthy value to run them.
+ """
+ return unittest.skipUnless(_run_slow_tests, "test is slow")(test_case)
+
+
+def require_cpu(test_case):
+ """
+ Decorator marking a test that must be only ran on the CPU. These tests are skipped when a GPU is available.
+ """
+ return unittest.skipUnless(torch_device == "cpu", "test requires only a CPU")(test_case)
+
+
+def require_non_cpu(test_case):
+ """
+ Decorator marking a test that requires a hardware accelerator backend. These tests are skipped when there are no
+ hardware accelerator available.
+ """
+ return unittest.skipUnless(torch_device != "cpu", "test requires a GPU")(test_case)
+
+
+def require_cuda(test_case):
+ """
+ Decorator marking a test that requires CUDA. These tests are skipped when there are no GPU available or when
+ TorchXLA is available.
+ """
+ return unittest.skipUnless(is_cuda_available() and not is_torch_xla_available(), "test requires a GPU")(test_case)
+
+
+def require_cuda_or_hpu(test_case):
+ """
+ Decorator marking a test that requires CUDA or HPU. These tests are skipped when there are no GPU available or when
+ TorchXLA is available.
+ """
+ return unittest.skipUnless(
+ (is_cuda_available() and not is_torch_xla_available()) or is_hpu_available(), "test requires a GPU or HPU"
+ )(test_case)
+
+
+def require_xpu(test_case):
+ """
+ Decorator marking a test that requires XPU. These tests are skipped when there are no XPU available.
+ """
+ return unittest.skipUnless(is_xpu_available(), "test requires a XPU")(test_case)
+
+
+def require_cuda_or_xpu(test_case):
+ """
+ Decorator marking a test that requires CUDA or XPU. These tests are skipped when there are no GPU available or when
+ TorchXLA is available.
+ """
+ cuda_condition = is_cuda_available() and not is_torch_xla_available()
+ xpu_condition = is_xpu_available()
+ return unittest.skipUnless(cuda_condition or xpu_condition, "test requires a CUDA GPU or XPU")(test_case)
+
+
+def require_non_xpu(test_case):
+ """
+ Decorator marking a test that should be skipped for XPU.
+ """
+ return unittest.skipUnless(torch_device != "xpu", "test requires a non-XPU")(test_case)
+
+
+def require_non_hpu(test_case):
+ """
+ Decorator marking a test that should be skipped for HPU.
+ """
+ return unittest.skipUnless(torch_device != "hpu", "test requires a non-HPU")(test_case)
+
+
+def require_fp16(test_case):
+ """
+ Decorator marking a test that requires FP16. These tests are skipped when FP16 is not supported.
+ """
+
+ return unittest.skipUnless(is_fp16_available(), "test requires FP16 support")(test_case)
+
+
+def require_fp8(test_case):
+ """
+ Decorator marking a test that requires FP8. These tests are skipped when FP8 is not supported.
+ """
+
+ # is_fp8_available only checks for libraries
+ # ideally it should check for device capability as well
+ fp8_is_available = is_fp8_available()
+
+ if torch.cuda.is_available() and not check_cuda_fp8_capability():
+ fp8_is_available = False
+
+ if is_hpu_available() and is_habana_gaudi1():
+ fp8_is_available = False
+
+ return unittest.skipUnless(fp8_is_available, "test requires FP8 support")(test_case)
+
+
+def require_fsdp2(test_case):
+ return unittest.skipUnless(is_torch_version(">=", "2.5.0"), "test requires FSDP2 (torch >= 2.5.0)")(test_case)
+
+
+def require_mlu(test_case):
+ """
+ Decorator marking a test that requires MLU. These tests are skipped when there are no MLU available.
+ """
+ return unittest.skipUnless(is_mlu_available(), "test require a MLU")(test_case)
+
+
+def require_sdaa(test_case):
+ """
+ Decorator marking a test that requires SDAA. These tests are skipped when there are no SDAA available.
+ """
+ return unittest.skipUnless(is_sdaa_available(), "test require a SDAA")(test_case)
+
+
+def require_musa(test_case):
+ """
+ Decorator marking a test that requires MUSA. These tests are skipped when there are no MUSA available.
+ """
+ return unittest.skipUnless(is_musa_available(), "test require a MUSA")(test_case)
+
+
+def require_npu(test_case):
+ """
+ Decorator marking a test that requires NPU. These tests are skipped when there are no NPU available.
+ """
+ return unittest.skipUnless(is_npu_available(), "test require a NPU")(test_case)
+
+
+def require_mps(test_case):
+ """
+ Decorator marking a test that requires MPS backend. These tests are skipped when torch doesn't support `mps`
+ backend.
+ """
+ return unittest.skipUnless(is_mps_available(), "test requires a `mps` backend support in `torch`")(test_case)
+
+
+def require_huggingface_suite(test_case):
+ """
+ Decorator marking a test that requires transformers and datasets. These tests are skipped when they are not.
+ """
+ return unittest.skipUnless(
+ is_transformers_available() and is_datasets_available(),
+ "test requires the Hugging Face suite",
+ )(test_case)
+
+
+def require_transformers(test_case):
+ """
+ Decorator marking a test that requires transformers. These tests are skipped when they are not.
+ """
+ return unittest.skipUnless(is_transformers_available(), "test requires the transformers library")(test_case)
+
+
+def require_timm(test_case):
+ """
+ Decorator marking a test that requires timm. These tests are skipped when they are not.
+ """
+ return unittest.skipUnless(is_timm_available(), "test requires the timm library")(test_case)
+
+
+def require_torchvision(test_case):
+ """
+ Decorator marking a test that requires torchvision. These tests are skipped when they are not.
+ """
+ return unittest.skipUnless(is_torchvision_available(), "test requires the torchvision library")(test_case)
+
+
+def require_triton(test_case):
+ """
+ Decorator marking a test that requires triton. These tests are skipped when they are not.
+ """
+ return unittest.skipUnless(is_triton_available(), "test requires the triton library")(test_case)
+
+
+def require_schedulefree(test_case):
+ """
+ Decorator marking a test that requires schedulefree. These tests are skipped when they are not.
+ """
+ return unittest.skipUnless(is_schedulefree_available(), "test requires the schedulefree library")(test_case)
+
+
+def require_bnb(test_case):
+ """
+ Decorator marking a test that requires bitsandbytes. These tests are skipped when they are not.
+ """
+ return unittest.skipUnless(is_bnb_available(), "test requires the bitsandbytes library")(test_case)
+
+
+def require_tpu(test_case):
+ """
+ Decorator marking a test that requires TPUs. These tests are skipped when there are no TPUs available.
+ """
+ return unittest.skipUnless(is_torch_xla_available(check_is_tpu=True), "test requires TPU")(test_case)
+
+
+def require_non_torch_xla(test_case):
+ """
+ Decorator marking a test as requiring an environment without TorchXLA. These tests are skipped when TorchXLA is
+ available.
+ """
+ return unittest.skipUnless(not is_torch_xla_available(), "test requires an env without TorchXLA")(test_case)
+
+
+def require_single_device(test_case):
+ """
+ Decorator marking a test that requires a single device. These tests are skipped when there is no hardware
+ accelerator available or number of devices is more than one.
+ """
+ return unittest.skipUnless(
+ torch_device != "cpu" and device_count == 1, "test requires a single device accelerator"
+ )(test_case)
+
+
+def require_single_gpu(test_case):
+ """
+ Decorator marking a test that requires CUDA on a single GPU. These tests are skipped when there are no GPU
+ available or number of GPUs is more than one.
+ """
+ return unittest.skipUnless(torch.cuda.device_count() == 1, "test requires a GPU")(test_case)
+
+
+def require_single_xpu(test_case):
+ """
+ Decorator marking a test that requires CUDA on a single XPU. These tests are skipped when there are no XPU
+ available or number of xPUs is more than one.
+ """
+ return unittest.skipUnless(torch.xpu.device_count() == 1, "test requires a XPU")(test_case)
+
+
+def require_multi_device(test_case):
+ """
+ Decorator marking a test that requires a multi-device setup. These tests are skipped on a machine without multiple
+ devices.
+ """
+ return unittest.skipUnless(device_count > 1, "test requires multiple hardware accelerators")(test_case)
+
+
+def require_multi_gpu(test_case):
+ """
+ Decorator marking a test that requires a multi-GPU setup. These tests are skipped on a machine without multiple
+ GPUs.
+ """
+ return unittest.skipUnless(torch.cuda.device_count() > 1, "test requires multiple GPUs")(test_case)
+
+
+def require_multi_xpu(test_case):
+ """
+ Decorator marking a test that requires a multi-XPU setup. These tests are skipped on a machine without multiple
+ XPUs.
+ """
+ return unittest.skipUnless(torch.xpu.device_count() > 1, "test requires multiple XPUs")(test_case)
+
+
+def require_multi_gpu_or_xpu(test_case):
+ """
+ Decorator marking a test that requires a multi-GPU setup. These tests are skipped on a machine without multiple
+ GPUs or XPUs.
+ """
+ return unittest.skipUnless(
+ (is_cuda_available() or is_xpu_available()) and device_count > 1, "test requires multiple GPUs or XPUs"
+ )(test_case)
+
+
+def require_deepspeed(test_case):
+ """
+ Decorator marking a test that requires DeepSpeed installed. These tests are skipped when DeepSpeed isn't installed
+ """
+ return unittest.skipUnless(is_deepspeed_available(), "test requires DeepSpeed")(test_case)
+
+
+def require_tp(test_case):
+ """
+ Decorator marking a test that requires TP installed. These tests are skipped when TP isn't installed
+ """
+ return unittest.skipUnless(
+ is_torch_version(">=", "2.3.0") and compare_versions("transformers", ">=", "4.52.0"),
+ "test requires torch version >= 2.3.0 and transformers version >= 4.52.0",
+ )(test_case)
+
+
+def require_torch_min_version(test_case=None, version=None):
+ """
+ Decorator marking that a test requires a particular torch version to be tested. These tests are skipped when an
+ installed torch version is less than the required one.
+ """
+ if test_case is None:
+ return partial(require_torch_min_version, version=version)
+ return unittest.skipUnless(is_torch_version(">=", version), f"test requires torch version >= {version}")(test_case)
+
+
+def require_tensorboard(test_case):
+ """
+ Decorator marking a test that requires tensorboard installed. These tests are skipped when tensorboard isn't
+ installed
+ """
+ return unittest.skipUnless(is_tensorboard_available(), "test requires Tensorboard")(test_case)
+
+
+def require_wandb(test_case):
+ """
+ Decorator marking a test that requires wandb installed. These tests are skipped when wandb isn't installed
+ """
+ return unittest.skipUnless(is_wandb_available(), "test requires wandb")(test_case)
+
+
+def require_trackio(test_case):
+ """
+ Decorator marking a test that requires trackio installed. These tests are skipped when trackio isn't installed
+ """
+ return unittest.skipUnless(is_trackio_available(), "test requires trackio")(test_case)
+
+
+def require_comet_ml(test_case):
+ """
+ Decorator marking a test that requires comet_ml installed. These tests are skipped when comet_ml isn't installed
+ """
+ return unittest.skipUnless(is_comet_ml_available(), "test requires comet_ml")(test_case)
+
+
+def require_aim(test_case):
+ """
+ Decorator marking a test that requires aim installed. These tests are skipped when aim isn't installed
+ """
+ return unittest.skipUnless(is_aim_available(), "test requires aim")(test_case)
+
+
+def require_clearml(test_case):
+ """
+ Decorator marking a test that requires clearml installed. These tests are skipped when clearml isn't installed
+ """
+ return unittest.skipUnless(is_clearml_available(), "test requires clearml")(test_case)
+
+
+def require_dvclive(test_case):
+ """
+ Decorator marking a test that requires dvclive installed. These tests are skipped when dvclive isn't installed
+ """
+ return unittest.skipUnless(is_dvclive_available(), "test requires dvclive")(test_case)
+
+
+def require_swanlab(test_case):
+ """
+ Decorator marking a test that requires swanlab installed. These tests are skipped when swanlab isn't installed
+ """
+ return unittest.skipUnless(is_swanlab_available(), "test requires swanlab")(test_case)
+
+
+def require_pandas(test_case):
+ """
+ Decorator marking a test that requires pandas installed. These tests are skipped when pandas isn't installed
+ """
+ return unittest.skipUnless(is_pandas_available(), "test requires pandas")(test_case)
+
+
+def require_mlflow(test_case):
+ """
+ Decorator marking a test that requires mlflow installed. These tests are skipped when mlflow isn't installed
+ """
+ return unittest.skipUnless(is_mlflow_available(), "test requires mlflow")(test_case)
+
+
+def require_pippy(test_case):
+ """
+ Decorator marking a test that requires pippy installed. These tests are skipped when pippy isn't installed It is
+ also checked if the test is running on a Gaudi1 device which doesn't support pippy.
+ """
+ return unittest.skipUnless(is_pippy_available() and not is_habana_gaudi1(), "test requires pippy")(test_case)
+
+
+def require_import_timer(test_case):
+ """
+ Decorator marking a test that requires tuna interpreter installed. These tests are skipped when tuna isn't
+ installed
+ """
+ return unittest.skipUnless(is_import_timer_available(), "test requires tuna interpreter")(test_case)
+
+
+def require_transformer_engine(test_case):
+ """
+ Decorator marking a test that requires transformers engine installed. These tests are skipped when transformers
+ engine isn't installed
+ """
+ return unittest.skipUnless(is_transformer_engine_available(), "test requires transformers engine")(test_case)
+
+
+def require_transformer_engine_mxfp8(test_case):
+ """
+ Decorator marking a test that requires transformers engine MXFP8 block scaling available. These tests are skipped
+ when transformers engine MXFP8 block scaling isn't available
+ """
+ return unittest.skipUnless(
+ is_transformer_engine_mxfp8_available(), "test requires transformers engine MXFP8 block scaling"
+ )(test_case)
+
+
+def require_torchao(test_case):
+ """
+ Decorator marking a test that requires torchao installed. These tests are skipped when torchao isn't installed
+ """
+ return unittest.skipUnless(is_torchao_available(), "test requires torchao")(test_case)
+
+
+def require_matplotlib(test_case):
+ """
+ Decorator marking a test that requires matplotlib installed. These tests are skipped when matplotlib isn't
+ installed
+ """
+ return unittest.skipUnless(is_matplotlib_available(), "test requires matplotlib")(test_case)
+
+
+_atleast_one_tracker_available = (
+ any([is_wandb_available(), is_tensorboard_available(), is_trackio_available(), is_swanlab_available()])
+ and not is_comet_ml_available()
+)
+
+
+def require_trackers(test_case):
+ """
+ Decorator marking that a test requires at least one tracking library installed. These tests are skipped when none
+ are installed
+ """
+ return unittest.skipUnless(
+ _atleast_one_tracker_available,
+ "test requires at least one tracker to be available and for `comet_ml` to not be installed",
+ )(test_case)
+
+
+def require_torchdata_stateful_dataloader(test_case):
+ """
+ Decorator marking a test that requires torchdata.stateful_dataloader.
+
+ These tests are skipped when torchdata with stateful_dataloader module isn't installed.
+
+ """
+ return unittest.skipUnless(
+ is_torchdata_stateful_dataloader_available(), "test requires torchdata.stateful_dataloader"
+ )(test_case)
+
+
+def run_first(test_case):
+ """
+ Decorator marking a test with order(1). When pytest-order plugin is installed, tests marked with this decorator are
+ guaranteed to run first.
+
+ This is especially useful in some test settings like on a Gaudi instance where a Gaudi device can only be used by a
+ single process at a time. So we make sure all tests that run in a subprocess are launched first, to avoid device
+ allocation conflicts.
+
+ If pytest is not installed, test will be returned as is.
+ """
+
+ if is_pytest_available():
+ import pytest
+
+ return pytest.mark.order(1)(test_case)
+ return test_case
+
+
+class TempDirTestCase(unittest.TestCase):
+ """
+ A TestCase class that keeps a single `tempfile.TemporaryDirectory` open for the duration of the class, wipes its
+ data at the start of a test, and then destroys it at the end of the TestCase.
+
+ Useful for when a class or API requires a single constant folder throughout it's use, such as Weights and Biases
+
+ The temporary directory location will be stored in `self.tmpdir`
+ """
+
+ clear_on_setup = True
+
+ @classmethod
+ def setUpClass(cls):
+ "Creates a `tempfile.TemporaryDirectory` and stores it in `cls.tmpdir`"
+ cls.tmpdir = Path(tempfile.mkdtemp())
+
+ @classmethod
+ def tearDownClass(cls):
+ "Remove `cls.tmpdir` after test suite has finished"
+ if os.path.exists(cls.tmpdir):
+ shutil.rmtree(cls.tmpdir)
+
+ def setUp(self):
+ "Destroy all contents in `self.tmpdir`, but not `self.tmpdir`"
+ if self.clear_on_setup:
+ for path in self.tmpdir.glob("**/*"):
+ if path.is_file():
+ path.unlink()
+ elif path.is_dir():
+ shutil.rmtree(path)
+
+
+class AccelerateTestCase(unittest.TestCase):
+ """
+ A TestCase class that will reset the accelerator state at the end of every test. Every test that checks or utilizes
+ the `AcceleratorState` class should inherit from this to avoid silent failures due to state being shared between
+ tests.
+ """
+
+ def tearDown(self):
+ super().tearDown()
+ # Reset the state of the AcceleratorState singleton.
+ AcceleratorState._reset_state(True)
+
+
+class MockingTestCase(unittest.TestCase):
+ """
+ A TestCase class designed to dynamically add various mockers that should be used in every test, mimicking the
+ behavior of a class-wide mock when defining one normally will not do.
+
+ Useful when a mock requires specific information available only initialized after `TestCase.setUpClass`, such as
+ setting an environment variable with that information.
+
+ The `add_mocks` function should be ran at the end of a `TestCase`'s `setUp` function, after a call to
+ `super().setUp()` such as:
+ ```python
+ def setUp(self):
+ super().setUp()
+ mocks = mock.patch.dict(os.environ, {"SOME_ENV_VAR", "SOME_VALUE"})
+ self.add_mocks(mocks)
+ ```
+ """
+
+ def add_mocks(self, mocks: Union[mock.Mock, list[mock.Mock]]):
+ """
+ Add custom mocks for tests that should be repeated on each test. Should be called during
+ `MockingTestCase.setUp`, after `super().setUp()`.
+
+ Args:
+ mocks (`mock.Mock` or list of `mock.Mock`):
+ Mocks that should be added to the `TestCase` after `TestCase.setUpClass` has been run
+ """
+ self.mocks = mocks if isinstance(mocks, (tuple, list)) else [mocks]
+ for m in self.mocks:
+ m.start()
+ self.addCleanup(m.stop)
+
+
+def are_the_same_tensors(tensor):
+ state = AcceleratorState()
+ tensor = tensor[None].clone().to(state.device)
+ tensors = gather(tensor).cpu()
+ tensor = tensor[0].cpu()
+ for i in range(tensors.shape[0]):
+ if not torch.equal(tensors[i], tensor):
+ return False
+ return True
+
+
+class _RunOutput:
+ def __init__(self, returncode, stdout, stderr):
+ self.returncode = returncode
+ self.stdout = stdout
+ self.stderr = stderr
+
+
+async def _read_stream(stream, callback):
+ while True:
+ line = await stream.readline()
+ if line:
+ callback(line)
+ else:
+ break
+
+
+async def _stream_subprocess(cmd, env=None, stdin=None, timeout=None, quiet=False, echo=False) -> _RunOutput:
+ if echo:
+ print("\nRunning: ", " ".join(cmd))
+
+ p = await asyncio.create_subprocess_exec(
+ cmd[0],
+ *cmd[1:],
+ stdin=stdin,
+ stdout=asyncio.subprocess.PIPE,
+ stderr=asyncio.subprocess.PIPE,
+ env=env,
+ )
+
+ # note: there is a warning for a possible deadlock when using `wait` with huge amounts of data in the pipe
+ # https://docs.python.org/3/library/asyncio-subprocess.html#asyncio.asyncio.subprocess.Process.wait
+ #
+ # If it starts hanging, will need to switch to the following code. The problem is that no data
+ # will be seen until it's done and if it hangs for example there will be no debug info.
+ # out, err = await p.communicate()
+ # return _RunOutput(p.returncode, out, err)
+
+ out = []
+ err = []
+
+ def tee(line, sink, pipe, label=""):
+ line = line.decode("utf-8").rstrip()
+ sink.append(line)
+ if not quiet:
+ print(label, line, file=pipe)
+
+ # XXX: the timeout doesn't seem to make any difference here
+ await asyncio.wait(
+ [
+ asyncio.create_task(_read_stream(p.stdout, lambda l: tee(l, out, sys.stdout, label="stdout:"))),
+ asyncio.create_task(_read_stream(p.stderr, lambda l: tee(l, err, sys.stderr, label="stderr:"))),
+ ],
+ timeout=timeout,
+ )
+ return _RunOutput(await p.wait(), out, err)
+
+
+def execute_subprocess_async(cmd: list, env=None, stdin=None, timeout=180, quiet=False, echo=True) -> _RunOutput:
+ # Cast every path in `cmd` to a string
+ for i, c in enumerate(cmd):
+ if isinstance(c, Path):
+ cmd[i] = str(c)
+ loop = asyncio.get_event_loop()
+ result = loop.run_until_complete(
+ _stream_subprocess(cmd, env=env, stdin=stdin, timeout=timeout, quiet=quiet, echo=echo)
+ )
+
+ cmd_str = " ".join(cmd)
+ if result.returncode > 0:
+ stderr = "\n".join(result.stderr)
+ raise RuntimeError(
+ f"'{cmd_str}' failed with returncode {result.returncode}\n\n"
+ f"The combined stderr from workers follows:\n{stderr}"
+ )
+
+ return result
+
+
+def pytest_xdist_worker_id():
+ """
+ Returns an int value of worker's numerical id under `pytest-xdist`'s concurrent workers `pytest -n N` regime, or 0
+ if `-n 1` or `pytest-xdist` isn't being used.
+ """
+ worker = os.environ.get("PYTEST_XDIST_WORKER", "gw0")
+ worker = re.sub(r"^gw", "", worker, 0, re.M)
+ return int(worker)
+
+
+def get_torch_dist_unique_port():
+ """
+ Returns a port number that can be fed to `torch.distributed.launch`'s `--master_port` argument.
+
+ Under `pytest-xdist` it adds a delta number based on a worker id so that concurrent tests don't try to use the same
+ port at once.
+ """
+ port = 29500
+ uniq_delta = pytest_xdist_worker_id()
+ return port + uniq_delta
+
+
+class SubprocessCallException(Exception):
+ pass
+
+
+def run_command(command: list[str], return_stdout=False, env=None):
+ """
+ Runs `command` with `subprocess.check_output` and will potentially return the `stdout`. Will also properly capture
+ if an error occurred while running `command`
+ """
+ # Cast every path in `command` to a string
+ for i, c in enumerate(command):
+ if isinstance(c, Path):
+ command[i] = str(c)
+ if env is None:
+ env = os.environ.copy()
+ try:
+ output = subprocess.check_output(command, stderr=subprocess.STDOUT, env=env)
+ if return_stdout:
+ if hasattr(output, "decode"):
+ output = output.decode("utf-8")
+ return output
+ except subprocess.CalledProcessError as e:
+ raise SubprocessCallException(
+ f"Command `{' '.join(command)}` failed with the following error:\n\n{e.output.decode()}"
+ ) from e
+
+
+def path_in_accelerate_package(*components: str) -> Path:
+ """
+ Get a path within the `accelerate` package's directory.
+
+ Args:
+ *components: Components of the path to join after the package directory.
+
+ Returns:
+ `Path`: The path to the requested file or directory.
+ """
+
+ accelerate_package_dir = Path(inspect.getfile(accelerate)).parent
+ return accelerate_package_dir.joinpath(*components)
+
+
+@contextmanager
+def assert_exception(exception_class: Exception, msg: Optional[str] = None) -> bool:
+ """
+ Context manager to assert that the right `Exception` class was raised.
+
+ If `msg` is provided, will check that the message is contained in the raised exception.
+ """
+ was_ran = False
+ try:
+ yield
+ was_ran = True
+ except Exception as e:
+ assert isinstance(e, exception_class), f"Expected exception of type {exception_class} but got {type(e)}"
+ if msg is not None:
+ assert msg in str(e), f"Expected message '{msg}' to be in exception but got '{str(e)}'"
+ if was_ran:
+ raise AssertionError(f"Expected exception of type {exception_class} but ran without issue.")
+
+
+def capture_call_output(func, *args, **kwargs):
+ """
+ Takes in a `func` with `args` and `kwargs` and returns the captured stdout as a string
+ """
+ captured_output = io.StringIO()
+ original_stdout = sys.stdout
+ try:
+ sys.stdout = captured_output
+ func(*args, **kwargs)
+ except Exception as e:
+ raise e
+ finally:
+ sys.stdout = original_stdout
+ return captured_output.getvalue()
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/training.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/training.py
new file mode 100644
index 0000000000000000000000000000000000000000..c5e56a50dfa02c093fc0a8f11464ca57a3238ad1
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/test_utils/training.py
@@ -0,0 +1,148 @@
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import numpy as np
+import torch
+from torch.utils.data import DataLoader
+
+from accelerate.utils.dataclasses import DistributedType
+
+
+class RegressionDataset:
+ def __init__(self, a=2, b=3, length=64, seed=None):
+ rng = np.random.default_rng(seed)
+ self.length = length
+ self.x = rng.normal(size=(length,)).astype(np.float32)
+ self.y = a * self.x + b + rng.normal(scale=0.1, size=(length,)).astype(np.float32)
+
+ def __len__(self):
+ return self.length
+
+ def __getitem__(self, i):
+ return {"x": self.x[i], "y": self.y[i]}
+
+
+class RegressionModel(torch.nn.Module):
+ def __init__(self, a=0, b=0, double_output=False):
+ super().__init__()
+ self.a = torch.nn.Parameter(torch.tensor(a).float())
+ self.b = torch.nn.Parameter(torch.tensor(b).float())
+ self.first_batch = True
+
+ def forward(self, x=None):
+ if self.first_batch:
+ print(f"Model dtype: {self.a.dtype}, {self.b.dtype}. Input dtype: {x.dtype}")
+ self.first_batch = False
+ return x * self.a + self.b
+
+
+def mocked_dataloaders(accelerator, batch_size: int = 16):
+ from datasets import load_dataset
+ from transformers import AutoTokenizer
+
+ tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
+ data_files = {"train": "tests/test_samples/MRPC/train.csv", "validation": "tests/test_samples/MRPC/dev.csv"}
+ datasets = load_dataset("csv", data_files=data_files)
+ label_list = datasets["train"].unique("label")
+
+ label_to_id = {v: i for i, v in enumerate(label_list)}
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(
+ examples["sentence1"], examples["sentence2"], truncation=True, max_length=None, padding="max_length"
+ )
+ if "label" in examples:
+ outputs["labels"] = [label_to_id[l] for l in examples["label"]]
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["sentence1", "sentence2", "label"],
+ )
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ if accelerator.distributed_type == DistributedType.XLA:
+ return tokenizer.pad(examples, padding="max_length", max_length=128, return_tensors="pt")
+ return tokenizer.pad(examples, padding="longest", return_tensors="pt")
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=2)
+ eval_dataloader = DataLoader(tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=1)
+
+ return train_dataloader, eval_dataloader
+
+
+def mocked_dataloaders_for_autoregressive_models(accelerator, batch_size: int = 16):
+ from datasets import load_dataset
+ from transformers import AutoTokenizer
+
+ tokenizer = AutoTokenizer.from_pretrained("HuggingFaceTB/SmolLM-360M")
+ tokenizer.pad_token = tokenizer.eos_token
+
+ data_files = {"train": "tests/test_samples/MRPC/train.csv", "validation": "tests/test_samples/MRPC/dev.csv"}
+ datasets = load_dataset("csv", data_files=data_files)
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], truncation=True, max_length=None, return_attention_mask=False)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["sentence1", "sentence2", "label"],
+ )
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ max_length = (
+ 128
+ if accelerator.distributed_type == DistributedType.XLA
+ else max([len(e["input_ids"]) for e in examples])
+ )
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ batch = tokenizer.pad(
+ examples,
+ padding="max_length",
+ max_length=max_length + 1,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ batch["labels"] = batch["input_ids"][:, 1:]
+ batch["input_ids"] = batch["input_ids"][:, :-1]
+
+ batch["labels"] = torch.where(batch["labels"] == tokenizer.pad_token_id, -100, batch["labels"])
+
+ return batch
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(tokenized_datasets["train"], shuffle=False, collate_fn=collate_fn, batch_size=2)
+ eval_dataloader = DataLoader(tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=1)
+
+ return train_dataloader, eval_dataloader
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/tracking.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/tracking.py
new file mode 100644
index 0000000000000000000000000000000000000000..ecd722569fcde9956355dc6c81b96c1aac08ea20
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/tracking.py
@@ -0,0 +1,1326 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+# Expectation:
+# Provide a project dir name, then each type of logger gets stored in project/{`logging_dir`}
+
+import json
+import os
+import time
+from functools import wraps
+from typing import Any, Optional, Union
+
+import yaml
+from packaging import version
+
+from .logging import get_logger
+from .state import PartialState
+from .utils import (
+ LoggerType,
+ compare_versions,
+ is_aim_available,
+ is_clearml_available,
+ is_comet_ml_available,
+ is_dvclive_available,
+ is_mlflow_available,
+ is_swanlab_available,
+ is_tensorboard_available,
+ is_trackio_available,
+ is_wandb_available,
+ listify,
+)
+
+
+_available_trackers = []
+
+if is_tensorboard_available():
+ _available_trackers.append(LoggerType.TENSORBOARD)
+
+if is_wandb_available():
+ _available_trackers.append(LoggerType.WANDB)
+
+if is_comet_ml_available():
+ _available_trackers.append(LoggerType.COMETML)
+
+if is_aim_available():
+ _available_trackers.append(LoggerType.AIM)
+
+if is_mlflow_available():
+ _available_trackers.append(LoggerType.MLFLOW)
+
+if is_clearml_available():
+ _available_trackers.append(LoggerType.CLEARML)
+
+if is_dvclive_available():
+ _available_trackers.append(LoggerType.DVCLIVE)
+
+if is_swanlab_available():
+ _available_trackers.append(LoggerType.SWANLAB)
+
+if is_trackio_available():
+ _available_trackers.append(LoggerType.TRACKIO)
+
+logger = get_logger(__name__)
+
+
+def on_main_process(function):
+ """
+ Decorator to selectively run the decorated function on the main process only based on the `main_process_only`
+ attribute in a class.
+
+ Checks at function execution rather than initialization time, not triggering the initialization of the
+ `PartialState`.
+ """
+
+ @wraps(function)
+ def execute_on_main_process(self, *args, **kwargs):
+ if getattr(self, "main_process_only", False):
+ return PartialState().on_main_process(function)(self, *args, **kwargs)
+ else:
+ return function(self, *args, **kwargs)
+
+ return execute_on_main_process
+
+
+def get_available_trackers():
+ "Returns a list of all supported available trackers in the system"
+ return _available_trackers
+
+
+class GeneralTracker:
+ """
+ A base Tracker class to be used for all logging integration implementations.
+
+ Each function should take in `**kwargs` that will automatically be passed in from a base dictionary provided to
+ [`Accelerator`].
+
+ Should implement `name`, `requires_logging_directory`, and `tracker` properties such that:
+
+ `name` (`str`): String representation of the tracker class name, such as "TensorBoard" `requires_logging_directory`
+ (`bool`): Whether the logger requires a directory to store their logs. `tracker` (`object`): Should return internal
+ tracking mechanism used by a tracker class (such as the `run` for wandb)
+
+ Implementations can also include a `main_process_only` (`bool`) attribute to toggle if relevant logging, init, and
+ other functions should occur on the main process or across all processes (by default will use `True`)
+ """
+
+ main_process_only = True
+
+ def __init__(self, _blank=False):
+ if not _blank:
+ err = ""
+ if not hasattr(self, "name"):
+ err += "`name`"
+ if not hasattr(self, "requires_logging_directory"):
+ if len(err) > 0:
+ err += ", "
+ err += "`requires_logging_directory`"
+
+ # as tracker is a @property that relies on post-init
+ if "tracker" not in dir(self):
+ if len(err) > 0:
+ err += ", "
+ err += "`tracker`"
+ if len(err) > 0:
+ raise NotImplementedError(
+ f"The implementation for this tracker class is missing the following "
+ f"required attributes. Please define them in the class definition: "
+ f"{err}"
+ )
+
+ def start(self):
+ """
+ Lazy initialization of the tracker inside Accelerator to avoid initializing PartialState before
+ InitProcessGroupKwargs.
+ """
+ pass
+
+ def store_init_configuration(self, values: dict):
+ """
+ Logs `values` as hyperparameters for the run. Implementations should use the experiment configuration
+ functionality of a tracking API.
+
+ Args:
+ values (Dictionary `str` to `bool`, `str`, `float` or `int`):
+ Values to be stored as initial hyperparameters as key-value pairs. The values need to have type `bool`,
+ `str`, `float`, `int`, or `None`.
+ """
+ pass
+
+ def log(self, values: dict, step: Optional[int], **kwargs):
+ """
+ Logs `values` to the current run. Base `log` implementations of a tracking API should go in here, along with
+ special behavior for the `step parameter.
+
+ Args:
+ values (Dictionary `str` to `str`, `float`, or `int`):
+ Values to be logged as key-value pairs. The values need to have type `str`, `float`, or `int`.
+ step (`int`, *optional*):
+ The run step. If included, the log will be affiliated with this step.
+ """
+ pass
+
+ def finish(self):
+ """
+ Should run any finalizing functions within the tracking API. If the API should not have one, just don't
+ overwrite that method.
+ """
+ pass
+
+
+class TensorBoardTracker(GeneralTracker):
+ """
+ A `Tracker` class that supports `tensorboard`. Should be initialized at the start of your script.
+
+ Args:
+ run_name (`str`):
+ The name of the experiment run
+ logging_dir (`str`, `os.PathLike`):
+ Location for TensorBoard logs to be stored.
+ **kwargs (additional keyword arguments, *optional*):
+ Additional key word arguments passed along to the `tensorboard.SummaryWriter.__init__` method.
+ """
+
+ name = "tensorboard"
+ requires_logging_directory = True
+
+ def __init__(self, run_name: str, logging_dir: Union[str, os.PathLike], **kwargs):
+ super().__init__()
+ self.run_name = run_name
+ self.logging_dir_param = logging_dir
+ self.init_kwargs = kwargs
+
+ @on_main_process
+ def start(self):
+ try:
+ from torch.utils import tensorboard
+ except ModuleNotFoundError:
+ import tensorboardX as tensorboard
+ self.logging_dir = os.path.join(self.logging_dir_param, self.run_name)
+ self.writer = tensorboard.SummaryWriter(self.logging_dir, **self.init_kwargs)
+ logger.debug(f"Initialized TensorBoard project {self.run_name} logging to {self.logging_dir}")
+ logger.debug(
+ "Make sure to log any initial configurations with `self.store_init_configuration` before training!"
+ )
+
+ @property
+ def tracker(self):
+ return self.writer
+
+ @on_main_process
+ def store_init_configuration(self, values: dict):
+ """
+ Logs `values` as hyperparameters for the run. Should be run at the beginning of your experiment. Stores the
+ hyperparameters in a yaml file for future use.
+
+ Args:
+ values (Dictionary `str` to `bool`, `str`, `float` or `int`):
+ Values to be stored as initial hyperparameters as key-value pairs. The values need to have type `bool`,
+ `str`, `float`, `int`, or `None`.
+ """
+ self.writer.add_hparams(values, metric_dict={})
+ self.writer.flush()
+ project_run_name = time.time()
+ dir_name = os.path.join(self.logging_dir, str(project_run_name))
+ os.makedirs(dir_name, exist_ok=True)
+ with open(os.path.join(dir_name, "hparams.yml"), "w") as outfile:
+ try:
+ yaml.dump(values, outfile)
+ except yaml.representer.RepresenterError:
+ logger.error("Serialization to store hyperparameters failed")
+ raise
+ logger.debug("Stored initial configuration hyperparameters to TensorBoard and hparams yaml file")
+
+ @on_main_process
+ def log(self, values: dict, step: Optional[int] = None, **kwargs):
+ """
+ Logs `values` to the current run.
+
+ Args:
+ values (Dictionary `str` to `str`, `float`, `int` or `dict` of `str` to `float`/`int`):
+ Values to be logged as key-value pairs. The values need to have type `str`, `float`, `int` or `dict` of
+ `str` to `float`/`int`.
+ step (`int`, *optional*):
+ The run step. If included, the log will be affiliated with this step.
+ kwargs:
+ Additional key word arguments passed along to either `SummaryWriter.add_scaler`,
+ `SummaryWriter.add_text`, or `SummaryWriter.add_scalers` method based on the contents of `values`.
+ """
+ values = listify(values)
+ for k, v in values.items():
+ if isinstance(v, (int, float)):
+ self.writer.add_scalar(k, v, global_step=step, **kwargs)
+ elif isinstance(v, str):
+ self.writer.add_text(k, v, global_step=step, **kwargs)
+ elif isinstance(v, dict):
+ self.writer.add_scalars(k, v, global_step=step, **kwargs)
+ self.writer.flush()
+ logger.debug("Successfully logged to TensorBoard")
+
+ @on_main_process
+ def log_images(self, values: dict, step: Optional[int], **kwargs):
+ """
+ Logs `images` to the current run.
+
+ Args:
+ values (Dictionary `str` to `List` of `np.ndarray` or `PIL.Image`):
+ Values to be logged as key-value pairs. The values need to have type `List` of `np.ndarray` or
+ step (`int`, *optional*):
+ The run step. If included, the log will be affiliated with this step.
+ kwargs:
+ Additional key word arguments passed along to the `SummaryWriter.add_image` method.
+ """
+ for k, v in values.items():
+ self.writer.add_images(k, v, global_step=step, **kwargs)
+ logger.debug("Successfully logged images to TensorBoard")
+
+ @on_main_process
+ def finish(self):
+ """
+ Closes `TensorBoard` writer
+ """
+ self.writer.close()
+ logger.debug("TensorBoard writer closed")
+
+
+class WandBTracker(GeneralTracker):
+ """
+ A `Tracker` class that supports `wandb`. Should be initialized at the start of your script.
+
+ Args:
+ run_name (`str`):
+ The name of the experiment run.
+ **kwargs (additional keyword arguments, *optional*):
+ Additional key word arguments passed along to the `wandb.init` method.
+ """
+
+ name = "wandb"
+ requires_logging_directory = False
+ main_process_only = False
+
+ def __init__(self, run_name: str, **kwargs):
+ super().__init__()
+ self.run_name = run_name
+ self.init_kwargs = kwargs
+
+ @on_main_process
+ def start(self):
+ import wandb
+
+ self.run = wandb.init(project=self.run_name, **self.init_kwargs)
+ logger.debug(f"Initialized WandB project {self.run_name}")
+ logger.debug(
+ "Make sure to log any initial configurations with `self.store_init_configuration` before training!"
+ )
+
+ @property
+ def tracker(self):
+ return self.run
+
+ @on_main_process
+ def store_init_configuration(self, values: dict):
+ """
+ Logs `values` as hyperparameters for the run. Should be run at the beginning of your experiment.
+
+ Args:
+ values (Dictionary `str` to `bool`, `str`, `float` or `int`):
+ Values to be stored as initial hyperparameters as key-value pairs. The values need to have type `bool`,
+ `str`, `float`, `int`, or `None`.
+ """
+ import wandb
+
+ if os.environ.get("WANDB_MODE") == "offline":
+ # In offline mode, restart wandb with config included
+ if hasattr(self, "run") and self.run:
+ self.run.finish()
+
+ init_kwargs = self.init_kwargs.copy()
+ init_kwargs["config"] = values
+ self.run = wandb.init(project=self.run_name, **init_kwargs)
+ else:
+ wandb.config.update(values, allow_val_change=True)
+ logger.debug("Stored initial configuration hyperparameters to WandB")
+
+ @on_main_process
+ def log(self, values: dict, step: Optional[int] = None, **kwargs):
+ """
+ Logs `values` to the current run.
+
+ Args:
+ values (Dictionary `str` to `str`, `float`, `int` or `dict` of `str` to `float`/`int`):
+ Values to be logged as key-value pairs. The values need to have type `str`, `float`, `int` or `dict` of
+ `str` to `float`/`int`.
+ step (`int`, *optional*):
+ The run step. If included, the log will be affiliated with this step.
+ kwargs:
+ Additional key word arguments passed along to the `wandb.log` method.
+ """
+ self.run.log(values, step=step, **kwargs)
+ logger.debug("Successfully logged to WandB")
+
+ @on_main_process
+ def log_images(self, values: dict, step: Optional[int] = None, **kwargs):
+ """
+ Logs `images` to the current run.
+
+ Args:
+ values (Dictionary `str` to `List` of `np.ndarray` or `PIL.Image`):
+ Values to be logged as key-value pairs. The values need to have type `List` of `np.ndarray` or
+ step (`int`, *optional*):
+ The run step. If included, the log will be affiliated with this step.
+ kwargs:
+ Additional key word arguments passed along to the `wandb.log` method.
+ """
+ import wandb
+
+ for k, v in values.items():
+ self.log({k: [wandb.Image(image) for image in v]}, step=step, **kwargs)
+ logger.debug("Successfully logged images to WandB")
+
+ @on_main_process
+ def log_table(
+ self,
+ table_name: str,
+ columns: Optional[list[str]] = None,
+ data: Optional[list[list[Any]]] = None,
+ dataframe: Any = None,
+ step: Optional[int] = None,
+ **kwargs,
+ ):
+ """
+ Log a Table containing any object type (text, image, audio, video, molecule, html, etc). Can be defined either
+ with `columns` and `data` or with `dataframe`.
+
+ Args:
+ table_name (`str`):
+ The name to give to the logged table on the wandb workspace
+ columns (list of `str`, *optional*):
+ The name of the columns on the table
+ data (List of List of Any data type, *optional*):
+ The data to be logged in the table
+ dataframe (Any data type, *optional*):
+ The data to be logged in the table
+ step (`int`, *optional*):
+ The run step. If included, the log will be affiliated with this step.
+ """
+ import wandb
+
+ values = {table_name: wandb.Table(columns=columns, data=data, dataframe=dataframe)}
+ self.log(values, step=step, **kwargs)
+
+ @on_main_process
+ def finish(self):
+ """
+ Closes `wandb` writer
+ """
+ self.run.finish()
+ logger.debug("WandB run closed")
+
+
+class TrackioTracker(GeneralTracker):
+ """
+ A `Tracker` class that supports `trackio`. Should be initialized at the start of your script.
+
+ Args:
+ run_name (`str`):
+ The name of the experiment run. Will be used as the `project` name when instantiating trackio.
+ **kwargs (additional keyword arguments, *optional*):
+ Additional key word arguments passed along to the `trackio.init` method. Refer to this
+ [init](https://github.com/gradio-app/trackio/blob/814809552310468b13f84f33764f1369b4e5136c/trackio/__init__.py#L22)
+ to see all supported key word arguments.
+ """
+
+ name = "trackio"
+ requires_logging_directory = False
+ main_process_only = False
+
+ def __init__(self, run_name: str, **kwargs):
+ super().__init__()
+ self.run_name = run_name
+ self.init_kwargs = kwargs
+
+ @on_main_process
+ def start(self):
+ import trackio
+
+ self.run = trackio.init(project=self.run_name, **self.init_kwargs)
+ logger.debug(f"Initialized trackio project {self.run_name}")
+ logger.debug(
+ "Make sure to log any initial configurations with `self.store_init_configuration` before training!"
+ )
+
+ @property
+ def tracker(self):
+ return self.run
+
+ @on_main_process
+ def store_init_configuration(self, values: dict):
+ """
+ Logs `values` as hyperparameters for the run. Should be run at the beginning of your experiment.
+
+ Args:
+ values (Dictionary `str` to `bool`, `str`, `float` or `int`):
+ Values to be stored as initial hyperparameters as key-value pairs. The values need to have type `bool`,
+ `str`, `float`, `int`, or `None`.
+ """
+ import trackio
+
+ trackio.config.update(values, allow_val_change=True)
+ logger.debug("Stored initial configuration hyperparameters to trackio")
+
+ @on_main_process
+ def log(self, values: dict, step: Optional[int] = None, **kwargs):
+ """
+ Logs `values` to the current run.
+
+ Args:
+ values (Dictionary `str` to `str`, `float`, `int` or `dict` of `str` to `float`/`int`):
+ Values to be logged as key-value pairs. The values need to have type `str`, `float`, `int` or `dict` of
+ `str` to `float`/`int`.
+ step (`int`, *optional*):
+ The run step. If included, the log will be affiliated with this step.
+ kwargs:
+ Additional key word arguments passed along to the `trackio.log` method.
+ """
+ self.run.log(values, **kwargs)
+ logger.debug("Successfully logged to trackio")
+
+ @on_main_process
+ def finish(self):
+ """
+ Closes `trackio` run
+ """
+ self.run.finish()
+ logger.debug("trackio run closed")
+
+
+class CometMLTracker(GeneralTracker):
+ """
+ A `Tracker` class that supports `comet_ml`. Should be initialized at the start of your script.
+
+ API keys must be stored in a Comet config file.
+
+ Note:
+ For `comet_ml` versions < 3.41.0, additional keyword arguments are passed to `comet_ml.Experiment` instead:
+ https://www.comet.com/docs/v2/api-and-sdk/python-sdk/reference/Experiment/#comet_ml.Experiment.__init__
+
+ Args:
+ run_name (`str`):
+ The name of the experiment run.
+ **kwargs (additional keyword arguments, *optional*):
+ Additional key word arguments passed along to the `comet_ml.start` method:
+ https://www.comet.com/docs/v2/api-and-sdk/python-sdk/reference/start/
+ """
+
+ name = "comet_ml"
+ requires_logging_directory = False
+
+ def __init__(self, run_name: str, **kwargs):
+ super().__init__()
+ self.run_name = run_name
+ self.init_kwargs = kwargs
+
+ @on_main_process
+ def start(self):
+ import comet_ml
+
+ comet_version = version.parse(comet_ml.__version__)
+ if compare_versions(comet_version, ">=", "3.41.0"):
+ self.writer = comet_ml.start(project_name=self.run_name, **self.init_kwargs)
+ else:
+ logger.info("Update `comet_ml` (>=3.41.0) for experiment reuse and offline support.")
+ self.writer = comet_ml.Experiment(project_name=self.run_name, **self.init_kwargs)
+
+ logger.debug(f"Initialized CometML project {self.run_name}")
+ logger.debug(
+ "Make sure to log any initial configurations with `self.store_init_configuration` before training!"
+ )
+
+ @property
+ def tracker(self):
+ return self.writer
+
+ @on_main_process
+ def store_init_configuration(self, values: dict):
+ """
+ Logs `values` as hyperparameters for the run. Should be run at the beginning of your experiment.
+
+ Args:
+ values (Dictionary `str` to `bool`, `str`, `float` or `int`):
+ Values to be stored as initial hyperparameters as key-value pairs. The values need to have type `bool`,
+ `str`, `float`, `int`, or `None`.
+ """
+ self.writer.log_parameters(values)
+ logger.debug("Stored initial configuration hyperparameters to Comet")
+
+ @on_main_process
+ def log(self, values: dict, step: Optional[int] = None, **kwargs):
+ """
+ Logs `values` to the current run.
+
+ Args:
+ values (Dictionary `str` to `str`, `float`, `int` or `dict` of `str` to `float`/`int`):
+ Values to be logged as key-value pairs. The values need to have type `str`, `float`, `int` or `dict` of
+ `str` to `float`/`int`.
+ step (`int`, *optional*):
+ The run step. If included, the log will be affiliated with this step.
+ kwargs:
+ Additional key word arguments passed along to either `Experiment.log_metric`, `Experiment.log_other`,
+ or `Experiment.log_metrics` method based on the contents of `values`.
+ """
+ if step is not None:
+ self.writer.set_step(step)
+ for k, v in values.items():
+ if isinstance(v, (int, float)):
+ self.writer.log_metric(k, v, step=step, **kwargs)
+ elif isinstance(v, str):
+ self.writer.log_other(k, v, **kwargs)
+ elif isinstance(v, dict):
+ self.writer.log_metrics(v, step=step, **kwargs)
+ logger.debug("Successfully logged to Comet")
+
+ @on_main_process
+ def finish(self):
+ """
+ Flush `comet-ml` writer
+ """
+ self.writer.end()
+ logger.debug("Comet run flushed")
+
+
+class AimTracker(GeneralTracker):
+ """
+ A `Tracker` class that supports `aim`. Should be initialized at the start of your script.
+
+ Args:
+ run_name (`str`):
+ The name of the experiment run.
+ **kwargs (additional keyword arguments, *optional*):
+ Additional key word arguments passed along to the `Run.__init__` method.
+ """
+
+ name = "aim"
+ requires_logging_directory = True
+
+ def __init__(self, run_name: str, logging_dir: Optional[Union[str, os.PathLike]] = ".", **kwargs):
+ super().__init__()
+ self.run_name = run_name
+ self.aim_repo_path = logging_dir
+ self.init_kwargs = kwargs
+
+ @on_main_process
+ def start(self):
+ from aim import Run
+
+ self.writer = Run(repo=self.aim_repo_path, **self.init_kwargs)
+ self.writer.name = self.run_name
+ logger.debug(f"Initialized Aim project {self.run_name}")
+ logger.debug(
+ "Make sure to log any initial configurations with `self.store_init_configuration` before training!"
+ )
+
+ @property
+ def tracker(self):
+ return self.writer
+
+ @on_main_process
+ def store_init_configuration(self, values: dict):
+ """
+ Logs `values` as hyperparameters for the run. Should be run at the beginning of your experiment.
+
+ Args:
+ values (`dict`):
+ Values to be stored as initial hyperparameters as key-value pairs.
+ """
+ self.writer["hparams"] = values
+
+ @on_main_process
+ def log(self, values: dict, step: Optional[int], **kwargs):
+ """
+ Logs `values` to the current run.
+
+ Args:
+ values (`dict`):
+ Values to be logged as key-value pairs.
+ step (`int`, *optional*):
+ The run step. If included, the log will be affiliated with this step.
+ kwargs:
+ Additional key word arguments passed along to the `Run.track` method.
+ """
+ # Note: replace this with the dictionary support when merged
+ for key, value in values.items():
+ self.writer.track(value, name=key, step=step, **kwargs)
+
+ @on_main_process
+ def log_images(self, values: dict, step: Optional[int] = None, kwargs: Optional[dict[str, dict]] = None):
+ """
+ Logs `images` to the current run.
+
+ Args:
+ values (`Dict[str, Union[np.ndarray, PIL.Image, Tuple[np.ndarray, str], Tuple[PIL.Image, str]]]`):
+ Values to be logged as key-value pairs. The values need to have type `np.ndarray` or PIL.Image. If a
+ tuple is provided, the first element should be the image and the second element should be the caption.
+ step (`int`, *optional*):
+ The run step. If included, the log will be affiliated with this step.
+ kwargs (`Dict[str, dict]`):
+ Additional key word arguments passed along to the `Run.Image` and `Run.track` method specified by the
+ keys `aim_image` and `track`, respectively.
+ """
+ import aim
+
+ aim_image_kw = {}
+ track_kw = {}
+
+ if kwargs is not None:
+ aim_image_kw = kwargs.get("aim_image", {})
+ track_kw = kwargs.get("track", {})
+
+ for key, value in values.items():
+ if isinstance(value, tuple):
+ img, caption = value
+ else:
+ img, caption = value, ""
+ aim_image = aim.Image(img, caption=caption, **aim_image_kw)
+ self.writer.track(aim_image, name=key, step=step, **track_kw)
+
+ @on_main_process
+ def finish(self):
+ """
+ Closes `aim` writer
+ """
+ self.writer.close()
+
+
+class MLflowTracker(GeneralTracker):
+ """
+ A `Tracker` class that supports `mlflow`. Should be initialized at the start of your script.
+
+ Args:
+ experiment_name (`str`, *optional*):
+ Name of the experiment. Environment variable MLFLOW_EXPERIMENT_NAME has priority over this argument.
+ logging_dir (`str` or `os.PathLike`, defaults to `"."`):
+ Location for mlflow logs to be stored.
+ run_id (`str`, *optional*):
+ If specified, get the run with the specified UUID and log parameters and metrics under that run. The run’s
+ end time is unset and its status is set to running, but the run’s other attributes (source_version,
+ source_type, etc.) are not changed. Environment variable MLFLOW_RUN_ID has priority over this argument.
+ tags (`Dict[str, str]`, *optional*):
+ An optional `dict` of `str` keys and values, or a `str` dump from a `dict`, to set as tags on the run. If a
+ run is being resumed, these tags are set on the resumed run. If a new run is being created, these tags are
+ set on the new run. Environment variable MLFLOW_TAGS has priority over this argument.
+ nested_run (`bool`, *optional*, defaults to `False`):
+ Controls whether run is nested in parent run. True creates a nested run. Environment variable
+ MLFLOW_NESTED_RUN has priority over this argument.
+ run_name (`str`, *optional*):
+ Name of new run (stored as a mlflow.runName tag). Used only when `run_id` is unspecified.
+ description (`str`, *optional*):
+ An optional string that populates the description box of the run. If a run is being resumed, the
+ description is set on the resumed run. If a new run is being created, the description is set on the new
+ run.
+ """
+
+ name = "mlflow"
+ requires_logging_directory = False
+
+ def __init__(
+ self,
+ experiment_name: Optional[str] = None,
+ logging_dir: Optional[Union[str, os.PathLike]] = None,
+ run_id: Optional[str] = None,
+ tags: Optional[Union[dict[str, Any], str]] = None,
+ nested_run: Optional[bool] = False,
+ run_name: Optional[str] = None,
+ description: Optional[str] = None,
+ ):
+ experiment_name = os.environ.get("MLFLOW_EXPERIMENT_NAME", experiment_name)
+ run_id = os.environ.get("MLFLOW_RUN_ID", run_id)
+ tags = os.environ.get("MLFLOW_TAGS", tags)
+ if isinstance(tags, str):
+ tags = json.loads(tags)
+
+ nested_run = os.environ.get("MLFLOW_NESTED_RUN", nested_run)
+
+ self.experiment_name = experiment_name
+ self.logging_dir = logging_dir
+ self.run_id = run_id
+ self.tags = tags
+ self.nested_run = nested_run
+ self.run_name = run_name
+ self.description = description
+
+ @on_main_process
+ def start(self):
+ import mlflow
+
+ exps = mlflow.search_experiments(filter_string=f"name = '{self.experiment_name}'")
+ if len(exps) > 0:
+ if len(exps) > 1:
+ logger.warning("Multiple experiments with the same name found. Using first one.")
+ experiment_id = exps[0].experiment_id
+ else:
+ experiment_id = mlflow.create_experiment(
+ name=self.experiment_name,
+ artifact_location=self.logging_dir,
+ tags=self.tags,
+ )
+
+ self.active_run = mlflow.start_run(
+ run_id=self.run_id,
+ experiment_id=experiment_id,
+ run_name=self.run_name,
+ nested=self.nested_run,
+ tags=self.tags,
+ description=self.description,
+ )
+
+ logger.debug(f"Initialized mlflow experiment {self.experiment_name}")
+ logger.debug(
+ "Make sure to log any initial configurations with `self.store_init_configuration` before training!"
+ )
+
+ @property
+ def tracker(self):
+ return self.active_run
+
+ @on_main_process
+ def store_init_configuration(self, values: dict):
+ """
+ Logs `values` as hyperparameters for the run. Should be run at the beginning of your experiment.
+
+ Args:
+ values (`dict`):
+ Values to be stored as initial hyperparameters as key-value pairs.
+ """
+ import mlflow
+
+ for name, value in list(values.items()):
+ # internally, all values are converted to str in MLflow
+ if len(str(value)) > mlflow.utils.validation.MAX_PARAM_VAL_LENGTH:
+ logger.warning_once(
+ f'Accelerate is attempting to log a value of "{value}" for key "{name}" as a parameter. MLflow\'s'
+ f" log_param() only accepts values no longer than {mlflow.utils.validation.MAX_PARAM_VAL_LENGTH} characters so we dropped this attribute."
+ )
+ del values[name]
+
+ values_list = list(values.items())
+
+ # MLflow cannot log more than 100 values in one go, so we have to split it
+ for i in range(0, len(values_list), mlflow.utils.validation.MAX_PARAMS_TAGS_PER_BATCH):
+ mlflow.log_params(dict(values_list[i : i + mlflow.utils.validation.MAX_PARAMS_TAGS_PER_BATCH]))
+
+ logger.debug("Stored initial configuration hyperparameters to MLflow")
+
+ @on_main_process
+ def log(self, values: dict, step: Optional[int]):
+ """
+ Logs `values` to the current run.
+
+ Args:
+ values (`dict`):
+ Values to be logged as key-value pairs.
+ step (`int`, *optional*):
+ The run step. If included, the log will be affiliated with this step.
+ """
+ metrics = {}
+ for k, v in values.items():
+ if isinstance(v, (int, float)):
+ metrics[k] = v
+ else:
+ logger.warning_once(
+ f'MLflowTracker is attempting to log a value of "{v}" of type {type(v)} for key "{k}" as a metric. '
+ "MLflow's log_metric() only accepts float and int types so we dropped this attribute."
+ )
+ import mlflow
+
+ mlflow.log_metrics(metrics, step=step)
+ logger.debug("Successfully logged to mlflow")
+
+ @on_main_process
+ def log_figure(self, figure: Any, artifact_file: str, **save_kwargs):
+ """
+ Logs an figure to the current run.
+
+ Args:
+ figure (Any):
+ The figure to be logged.
+ artifact_file (`str`, *optional*):
+ The run-relative artifact file path in posixpath format to which the image is saved.
+ If not provided, the image is saved to a default location.
+ **kwargs:
+ Additional keyword arguments passed to the underlying mlflow.log_image function.
+ """
+ import mlflow
+
+ mlflow.log_figure(figure=figure, artifact_file=artifact_file, **save_kwargs)
+ logger.debug("Successfully logged image to mlflow")
+
+ @on_main_process
+ def log_artifacts(self, local_dir: str, artifact_path: Optional[str] = None):
+ """
+ Logs an artifacts (all content of a dir) to the current run.
+
+ local_dir (`str`):
+ Path to the directory to be logged as an artifact.
+ artifact_path (`str`, *optional*):
+ Directory within the run's artifact directory where the artifact will be logged. If omitted, the
+ artifact will be logged to the root of the run's artifact directory. The run step. If included, the
+ artifact will be affiliated with this step.
+ """
+ import mlflow
+
+ mlflow.log_artifacts(local_dir=local_dir, artifact_path=artifact_path)
+ logger.debug("Successfully logged artofact to mlflow")
+
+ @on_main_process
+ def log_artifact(self, local_path: str, artifact_path: Optional[str] = None):
+ """
+ Logs an artifact (file) to the current run.
+
+ local_path (`str`):
+ Path to the file to be logged as an artifact.
+ artifact_path (`str`, *optional*):
+ Directory within the run's artifact directory where the artifact will be logged. If omitted, the
+ artifact will be logged to the root of the run's artifact directory. The run step. If included, the
+ artifact will be affiliated with this step.
+ """
+ import mlflow
+
+ mlflow.log_artifact(local_path=local_path, artifact_path=artifact_path)
+ logger.debug("Successfully logged artofact to mlflow")
+
+ @on_main_process
+ def finish(self):
+ """
+ End the active MLflow run.
+ """
+ import mlflow
+
+ mlflow.end_run()
+
+
+class ClearMLTracker(GeneralTracker):
+ """
+ A `Tracker` class that supports `clearml`. Should be initialized at the start of your script.
+
+ Args:
+ run_name (`str`, *optional*):
+ Name of the experiment. Environment variables `CLEARML_PROJECT` and `CLEARML_TASK` have priority over this
+ argument.
+ **kwargs (additional keyword arguments, *optional*):
+ Kwargs passed along to the `Task.__init__` method.
+ """
+
+ name = "clearml"
+ requires_logging_directory = False
+
+ def __init__(self, run_name: Optional[str] = None, **kwargs):
+ super().__init__()
+ self.user_provided_run_name = run_name
+ self._initialized_externally = False
+ self.init_kwargs = kwargs
+
+ @on_main_process
+ def start(self):
+ from clearml import Task
+
+ current_task = Task.current_task()
+ if current_task:
+ self._initialized_externally = True
+ self.task = current_task
+ return
+
+ task_init_args = {**self.init_kwargs}
+ task_init_args.setdefault("project_name", os.environ.get("CLEARML_PROJECT", self.user_provided_run_name))
+ task_init_args.setdefault("task_name", os.environ.get("CLEARML_TASK", self.user_provided_run_name))
+ self.task = Task.init(**task_init_args)
+
+ @property
+ def tracker(self):
+ return self.task
+
+ @on_main_process
+ def store_init_configuration(self, values: dict):
+ """
+ Connect configuration dictionary to the Task object. Should be run at the beginning of your experiment.
+
+ Args:
+ values (`dict`):
+ Values to be stored as initial hyperparameters as key-value pairs.
+ """
+ return self.task.connect_configuration(values)
+
+ @on_main_process
+ def log(self, values: dict[str, Union[int, float]], step: Optional[int] = None, **kwargs):
+ """
+ Logs `values` dictionary to the current run. The dictionary keys must be strings. The dictionary values must be
+ ints or floats
+
+ Args:
+ values (`Dict[str, Union[int, float]]`):
+ Values to be logged as key-value pairs. If the key starts with 'eval_'/'test_'/'train_', the value will
+ be reported under the 'eval'/'test'/'train' series and the respective prefix will be removed.
+ Otherwise, the value will be reported under the 'train' series, and no prefix will be removed.
+ step (`int`, *optional*):
+ If specified, the values will be reported as scalars, with the iteration number equal to `step`.
+ Otherwise they will be reported as single values.
+ kwargs:
+ Additional key word arguments passed along to the `clearml.Logger.report_single_value` or
+ `clearml.Logger.report_scalar` methods.
+ """
+ clearml_logger = self.task.get_logger()
+ for k, v in values.items():
+ if not isinstance(v, (int, float)):
+ logger.warning_once(
+ "Accelerator is attempting to log a value of "
+ f'"{v}" of type {type(v)} for key "{k}" as a scalar. '
+ "This invocation of ClearML logger's report_scalar() "
+ "is incorrect so we dropped this attribute."
+ )
+ continue
+ if step is None:
+ clearml_logger.report_single_value(name=k, value=v, **kwargs)
+ continue
+ title, series = ClearMLTracker._get_title_series(k)
+ clearml_logger.report_scalar(title=title, series=series, value=v, iteration=step, **kwargs)
+
+ @on_main_process
+ def log_images(self, values: dict, step: Optional[int] = None, **kwargs):
+ """
+ Logs `images` to the current run.
+
+ Args:
+ values (`Dict[str, List[Union[np.ndarray, PIL.Image]]`):
+ Values to be logged as key-value pairs. The values need to have type `List` of `np.ndarray` or
+ step (`int`, *optional*):
+ The run step. If included, the log will be affiliated with this step.
+ kwargs:
+ Additional key word arguments passed along to the `clearml.Logger.report_image` method.
+ """
+ clearml_logger = self.task.get_logger()
+ for k, v in values.items():
+ title, series = ClearMLTracker._get_title_series(k)
+ clearml_logger.report_image(title=title, series=series, iteration=step, image=v, **kwargs)
+
+ @on_main_process
+ def log_table(
+ self,
+ table_name: str,
+ columns: Optional[list[str]] = None,
+ data: Optional[list[list[Any]]] = None,
+ dataframe: Any = None,
+ step: Optional[int] = None,
+ **kwargs,
+ ):
+ """
+ Log a Table to the task. Can be defined eitherwith `columns` and `data` or with `dataframe`.
+
+ Args:
+ table_name (`str`):
+ The name of the table
+ columns (list of `str`, *optional*):
+ The name of the columns on the table
+ data (List of List of Any data type, *optional*):
+ The data to be logged in the table. If `columns` is not specified, then the first entry in data will be
+ the name of the columns of the table
+ dataframe (Any data type, *optional*):
+ The data to be logged in the table
+ step (`int`, *optional*):
+ The run step. If included, the log will be affiliated with this step.
+ kwargs:
+ Additional key word arguments passed along to the `clearml.Logger.report_table` method.
+ """
+ to_report = dataframe
+ if dataframe is None:
+ if data is None:
+ raise ValueError(
+ "`ClearMLTracker.log_table` requires that `data` to be supplied if `dataframe` is `None`"
+ )
+ to_report = [columns] + data if columns else data
+ title, series = ClearMLTracker._get_title_series(table_name)
+ self.task.get_logger().report_table(title=title, series=series, table_plot=to_report, iteration=step, **kwargs)
+
+ @on_main_process
+ def finish(self):
+ """
+ Close the ClearML task. If the task was initialized externally (e.g. by manually calling `Task.init`), this
+ function is a noop
+ """
+ if self.task and not self._initialized_externally:
+ self.task.close()
+
+ @staticmethod
+ def _get_title_series(name):
+ for prefix in ["eval", "test", "train"]:
+ if name.startswith(prefix + "_"):
+ return name[len(prefix) + 1 :], prefix
+ return name, "train"
+
+
+class DVCLiveTracker(GeneralTracker):
+ """
+ A `Tracker` class that supports `dvclive`. Should be initialized at the start of your script.
+
+ Args:
+ run_name (`str`, *optional*):
+ Ignored for dvclive. See `kwargs` instead.
+ kwargs:
+ Additional key word arguments passed along to [`dvclive.Live()`](https://dvc.org/doc/dvclive/live).
+
+ Example:
+
+ ```py
+ from accelerate import Accelerator
+
+ accelerator = Accelerator(log_with="dvclive")
+ accelerator.init_trackers(project_name="my_project", init_kwargs={"dvclive": {"dir": "my_directory"}})
+ ```
+ """
+
+ name = "dvclive"
+ requires_logging_directory = False
+
+ def __init__(self, run_name: Optional[str] = None, live: Optional[Any] = None, **kwargs):
+ super().__init__()
+ self.live = live
+ self.init_kwargs = kwargs
+
+ @on_main_process
+ def start(self):
+ from dvclive import Live
+
+ self.live = self.live if self.live is not None else Live(**self.init_kwargs)
+
+ @property
+ def tracker(self):
+ return self.live
+
+ @on_main_process
+ def store_init_configuration(self, values: dict):
+ """
+ Logs `values` as hyperparameters for the run. Should be run at the beginning of your experiment. Stores the
+ hyperparameters in a yaml file for future use.
+
+ Args:
+ values (Dictionary `str` to `bool`, `str`, `float`, `int`, or a List or Dict of those types):
+ Values to be stored as initial hyperparameters as key-value pairs. The values need to have type `bool`,
+ `str`, `float`, or `int`.
+ """
+ self.live.log_params(values)
+
+ @on_main_process
+ def log(self, values: dict, step: Optional[int] = None, **kwargs):
+ """
+ Logs `values` to the current run.
+
+ Args:
+ values (Dictionary `str` to `str`, `float`, or `int`):
+ Values to be logged as key-value pairs. The values need to have type `str`, `float`, or `int`.
+ step (`int`, *optional*):
+ The run step. If included, the log will be affiliated with this step.
+ kwargs:
+ Additional key word arguments passed along to `dvclive.Live.log_metric()`.
+ """
+ from dvclive.plots import Metric
+
+ if step is not None:
+ self.live.step = step
+ for k, v in values.items():
+ if Metric.could_log(v):
+ self.live.log_metric(k, v, **kwargs)
+ else:
+ logger.warning_once(
+ "Accelerator attempted to log a value of "
+ f'"{v}" of type {type(v)} for key "{k}" as a scalar. '
+ "This invocation of DVCLive's Live.log_metric() "
+ "is incorrect so we dropped this attribute."
+ )
+ self.live.next_step()
+
+ @on_main_process
+ def finish(self):
+ """
+ Closes `dvclive.Live()`.
+ """
+ self.live.end()
+
+
+class SwanLabTracker(GeneralTracker):
+ """
+ A `Tracker` class that supports `swanlab`. Should be initialized at the start of your script.
+
+ Args:
+ run_name (`str`):
+ The name of the experiment run.
+ **kwargs (additional keyword arguments, *optional*):
+ Additional key word arguments passed along to the `swanlab.init` method.
+ """
+
+ name = "swanlab"
+ requires_logging_directory = False
+ main_process_only = False
+
+ def __init__(self, run_name: str, **kwargs):
+ super().__init__()
+ self.run_name = run_name
+ self.init_kwargs = kwargs
+
+ @on_main_process
+ def start(self):
+ import swanlab
+
+ self.run = swanlab.init(project=self.run_name, **self.init_kwargs)
+ swanlab.config["FRAMEWORK"] = "🤗Accelerate" # add accelerate logo in config
+ logger.debug(f"Initialized SwanLab project {self.run_name}")
+ logger.debug(
+ "Make sure to log any initial configurations with `self.store_init_configuration` before training!"
+ )
+
+ @property
+ def tracker(self):
+ return self.run
+
+ @on_main_process
+ def store_init_configuration(self, values: dict):
+ """
+ Logs `values` as hyperparameters for the run. Should be run at the beginning of your experiment.
+
+ Args:
+ values (Dictionary `str` to `bool`, `str`, `float` or `int`):
+ Values to be stored as initial hyperparameters as key-value pairs. The values need to have type `bool`,
+ `str`, `float`, `int`, or `None`.
+ """
+ import swanlab
+
+ swanlab.config.update(values, allow_val_change=True)
+ logger.debug("Stored initial configuration hyperparameters to SwanLab")
+
+ @on_main_process
+ def log(self, values: dict, step: Optional[int] = None, **kwargs):
+ """
+ Logs `values` to the current run.
+
+ Args:
+ data : Dict[str, DataType]
+ Data must be a dict. The key must be a string with 0-9, a-z, A-Z, " ", "_", "-", "/". The value must be a
+ `float`, `float convertible object`, `int` or `swanlab.data.BaseType`.
+ step : int, optional
+ The step number of the current data, if not provided, it will be automatically incremented.
+ If step is duplicated, the data will be ignored.
+ kwargs:
+ Additional key word arguments passed along to the `swanlab.log` method. Likes:
+ print_to_console : bool, optional
+ Whether to print the data to the console, the default is False.
+ """
+ self.run.log(values, step=step, **kwargs)
+ logger.debug("Successfully logged to SwanLab")
+
+ @on_main_process
+ def log_images(self, values: dict, step: Optional[int] = None, **kwargs):
+ """
+ Logs `images` to the current run.
+
+ Args:
+ values (Dictionary `str` to `List` of `np.ndarray` or `PIL.Image`):
+ Values to be logged as key-value pairs. The values need to have type `List` of `np.ndarray` or
+ step (`int`, *optional*):
+ The run step. If included, the log will be affiliated with this step.
+ kwargs:
+ Additional key word arguments passed along to the `swanlab.log` method. Likes:
+ print_to_console : bool, optional
+ Whether to print the data to the console, the default is False.
+ """
+ import swanlab
+
+ for k, v in values.items():
+ self.log({k: [swanlab.Image(image) for image in v]}, step=step, **kwargs)
+ logger.debug("Successfully logged images to SwanLab")
+
+ @on_main_process
+ def finish(self):
+ """
+ Closes `swanlab` writer
+ """
+ self.run.finish()
+ logger.debug("SwanLab run closed")
+
+
+LOGGER_TYPE_TO_CLASS = {
+ "aim": AimTracker,
+ "comet_ml": CometMLTracker,
+ "mlflow": MLflowTracker,
+ "tensorboard": TensorBoardTracker,
+ "wandb": WandBTracker,
+ "clearml": ClearMLTracker,
+ "dvclive": DVCLiveTracker,
+ "swanlab": SwanLabTracker,
+ "trackio": TrackioTracker,
+}
+
+
+def filter_trackers(
+ log_with: list[Union[str, LoggerType, GeneralTracker]],
+ logging_dir: Optional[Union[str, os.PathLike]] = None,
+):
+ """
+ Takes in a list of potential tracker types and checks that:
+ - The tracker wanted is available in that environment
+ - Filters out repeats of tracker types
+ - If `all` is in `log_with`, will return all trackers in the environment
+ - If a tracker requires a `logging_dir`, ensures that `logging_dir` is not `None`
+
+ Args:
+ log_with (list of `str`, [`~utils.LoggerType`] or [`~tracking.GeneralTracker`], *optional*):
+ A list of loggers to be setup for experiment tracking. Should be one or several of:
+
+ - `"all"`
+ - `"tensorboard"`
+ - `"wandb"`
+ - `"trackio"`
+ - `"aim"`
+ - `"comet_ml"`
+ - `"mlflow"`
+ - `"dvclive"`
+ - `"swanlab"`
+ If `"all"` is selected, will pick up all available trackers in the environment and initialize them. Can
+ also accept implementations of `GeneralTracker` for custom trackers, and can be combined with `"all"`.
+ logging_dir (`str`, `os.PathLike`, *optional*):
+ A path to a directory for storing logs of locally-compatible loggers.
+ """
+ loggers = []
+ if log_with is not None:
+ if not isinstance(log_with, (list, tuple)):
+ log_with = [log_with]
+ if "all" in log_with or LoggerType.ALL in log_with:
+ loggers = [o for o in log_with if issubclass(type(o), GeneralTracker)] + get_available_trackers()
+ else:
+ for log_type in log_with:
+ if log_type not in LoggerType and not issubclass(type(log_type), GeneralTracker):
+ raise ValueError(f"Unsupported logging capability: {log_type}. Choose between {LoggerType.list()}")
+ if issubclass(type(log_type), GeneralTracker):
+ loggers.append(log_type)
+ else:
+ log_type = LoggerType(log_type)
+ if log_type not in loggers:
+ if log_type in get_available_trackers():
+ tracker_init = LOGGER_TYPE_TO_CLASS[str(log_type)]
+ if tracker_init.requires_logging_directory:
+ if logging_dir is None:
+ raise ValueError(
+ f"Logging with `{log_type}` requires a `logging_dir` to be passed in."
+ )
+ loggers.append(log_type)
+ else:
+ logger.debug(f"Tried adding logger {log_type}, but package is unavailable in the system.")
+
+ return loggers
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/__init__.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..d9696b1bb2aa5f944e8df4f54b3f4e9201d0d9ba
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/__init__.py
@@ -0,0 +1,306 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from ..parallelism_config import ParallelismConfig
+from .ao import convert_model_to_fp8_ao, filter_first_and_last_linear_layers, has_ao_layers
+from .constants import (
+ MITA_PROFILING_AVAILABLE_PYTORCH_VERSION,
+ MODEL_NAME,
+ OPTIMIZER_NAME,
+ PROFILE_PATTERN_NAME,
+ RNG_STATE_NAME,
+ SAFE_MODEL_NAME,
+ SAFE_WEIGHTS_INDEX_NAME,
+ SAFE_WEIGHTS_NAME,
+ SAFE_WEIGHTS_PATTERN_NAME,
+ SAMPLER_NAME,
+ SCALER_NAME,
+ SCHEDULER_NAME,
+ TORCH_DISTRIBUTED_OPERATION_TYPES,
+ TORCH_LAUNCH_PARAMS,
+ WEIGHTS_INDEX_NAME,
+ WEIGHTS_NAME,
+ WEIGHTS_PATTERN_NAME,
+ XPU_PROFILING_AVAILABLE_PYTORCH_VERSION,
+)
+from .dataclasses import (
+ AORecipeKwargs,
+ AutocastKwargs,
+ BnbQuantizationConfig,
+ ComputeEnvironment,
+ CustomDtype,
+ DataLoaderConfiguration,
+ DDPCommunicationHookType,
+ DeepSpeedPlugin,
+ DeepSpeedSequenceParallelConfig,
+ DistributedDataParallelKwargs,
+ DistributedType,
+ DynamoBackend,
+ FP8RecipeKwargs,
+ FullyShardedDataParallelPlugin,
+ GradientAccumulationPlugin,
+ GradScalerKwargs,
+ InitProcessGroupKwargs,
+ KwargsHandler,
+ LoggerType,
+ MegatronLMPlugin,
+ MSAMPRecipeKwargs,
+ PrecisionType,
+ ProfileKwargs,
+ ProjectConfiguration,
+ RNGType,
+ SageMakerDistributedType,
+ TensorInformation,
+ TERecipeKwargs,
+ TorchContextParallelConfig,
+ TorchDynamoPlugin,
+ TorchTensorParallelConfig,
+ TorchTensorParallelPlugin,
+ add_model_config_to_megatron_parser,
+)
+from .environment import (
+ are_libraries_initialized,
+ check_cuda_fp8_capability,
+ check_cuda_p2p_ib_support,
+ clear_environment,
+ convert_dict_to_env_variables,
+ get_cpu_distributed_information,
+ get_current_device_type,
+ get_gpu_info,
+ get_int_from_env,
+ parse_choice_from_env,
+ parse_flag_from_env,
+ patch_environment,
+ purge_accelerate_environment,
+ set_numa_affinity,
+ str_to_bool,
+)
+from .imports import (
+ deepspeed_required,
+ get_ccl_version,
+ is_4bit_bnb_available,
+ is_8bit_bnb_available,
+ is_aim_available,
+ is_bf16_available,
+ is_bitsandbytes_multi_backend_available,
+ is_bnb_available,
+ is_boto3_available,
+ is_ccl_available,
+ is_clearml_available,
+ is_comet_ml_available,
+ is_cuda_available,
+ is_datasets_available,
+ is_deepspeed_available,
+ is_dvclive_available,
+ is_fp8_available,
+ is_fp16_available,
+ is_habana_gaudi1,
+ is_hpu_available,
+ is_import_timer_available,
+ is_ipex_available,
+ is_lomo_available,
+ is_matplotlib_available,
+ is_megatron_lm_available,
+ is_mlflow_available,
+ is_mlu_available,
+ is_mps_available,
+ is_msamp_available,
+ is_musa_available,
+ is_npu_available,
+ is_pandas_available,
+ is_peft_available,
+ is_pippy_available,
+ is_pynvml_available,
+ is_pytest_available,
+ is_rich_available,
+ is_sagemaker_available,
+ is_schedulefree_available,
+ is_sdaa_available,
+ is_swanlab_available,
+ is_tensorboard_available,
+ is_timm_available,
+ is_torch_xla_available,
+ is_torchao_available,
+ is_torchdata_available,
+ is_torchdata_stateful_dataloader_available,
+ is_torchvision_available,
+ is_trackio_available,
+ is_transformer_engine_available,
+ is_transformer_engine_mxfp8_available,
+ is_transformers_available,
+ is_triton_available,
+ is_wandb_available,
+ is_weights_only_available,
+ is_xccl_available,
+ is_xpu_available,
+ torchao_required,
+)
+from .modeling import (
+ align_module_device,
+ calculate_maximum_sizes,
+ check_device_map,
+ check_tied_parameters_in_config,
+ check_tied_parameters_on_same_device,
+ compute_module_sizes,
+ convert_file_size_to_int,
+ dtype_byte_size,
+ find_tied_parameters,
+ get_balanced_memory,
+ get_grad_scaler,
+ get_max_layer_size,
+ get_max_memory,
+ get_mixed_precision_context_manager,
+ has_offloaded_params,
+ id_tensor_storage,
+ infer_auto_device_map,
+ is_peft_model,
+ load_checkpoint_in_model,
+ load_offloaded_weights,
+ load_state_dict,
+ named_module_tensors,
+ retie_parameters,
+ set_module_tensor_to_device,
+)
+from .offload import (
+ OffloadedWeightsLoader,
+ PrefixedDataset,
+ extract_submodules_state_dict,
+ load_offloaded_weight,
+ offload_state_dict,
+ offload_weight,
+ save_offload_index,
+)
+from .operations import (
+ CannotPadNestedTensorWarning,
+ GatheredParameters,
+ broadcast,
+ broadcast_object_list,
+ concatenate,
+ convert_outputs_to_fp32,
+ convert_to_fp32,
+ copy_tensor_to_devices,
+ find_batch_size,
+ find_device,
+ gather,
+ gather_object,
+ get_data_structure,
+ honor_type,
+ ignorant_find_batch_size,
+ initialize_tensors,
+ is_namedtuple,
+ is_tensor_information,
+ is_torch_tensor,
+ listify,
+ pad_across_processes,
+ pad_input_tensors,
+ recursively_apply,
+ reduce,
+ send_to_device,
+ slice_tensors,
+)
+from .versions import compare_versions, is_torch_version
+
+
+if is_deepspeed_available():
+ from .deepspeed import (
+ DeepSpeedEngineWrapper,
+ DeepSpeedOptimizerWrapper,
+ DeepSpeedSchedulerWrapper,
+ DummyOptim,
+ DummyScheduler,
+ HfDeepSpeedConfig,
+ get_active_deepspeed_plugin,
+ map_pytorch_optim_to_deepspeed,
+ )
+
+from .bnb import has_4bit_bnb_layers, load_and_quantize_model
+from .fsdp_utils import (
+ disable_fsdp_ram_efficient_loading,
+ enable_fsdp_ram_efficient_loading,
+ ensure_weights_retied,
+ fsdp2_apply_ac,
+ fsdp2_canonicalize_names,
+ fsdp2_load_full_state_dict,
+ fsdp2_prepare_model,
+ fsdp2_switch_optimizer_parameters,
+ get_fsdp2_grad_scaler,
+ load_fsdp_model,
+ load_fsdp_optimizer,
+ merge_fsdp_weights,
+ save_fsdp_model,
+ save_fsdp_optimizer,
+)
+from .launch import (
+ PrepareForLaunch,
+ _filter_args,
+ prepare_deepspeed_cmd_env,
+ prepare_multi_gpu_env,
+ prepare_sagemager_args_inputs,
+ prepare_simple_launcher_cmd_env,
+ prepare_tpu,
+)
+
+# For docs
+from .megatron_lm import (
+ AbstractTrainStep,
+ BertTrainStep,
+ GPTTrainStep,
+ MegatronLMDummyDataLoader,
+ MegatronLMDummyScheduler,
+ T5TrainStep,
+ avg_losses_across_data_parallel_group,
+)
+
+
+if is_megatron_lm_available():
+ from .megatron_lm import (
+ MegatronEngine,
+ MegatronLMOptimizerWrapper,
+ MegatronLMSchedulerWrapper,
+ gather_across_data_parallel_groups,
+ )
+ from .megatron_lm import initialize as megatron_lm_initialize
+ from .megatron_lm import prepare_data_loader as megatron_lm_prepare_data_loader
+ from .megatron_lm import prepare_model_optimizer_scheduler as megatron_lm_prepare_model_optimizer_scheduler
+ from .megatron_lm import prepare_optimizer as megatron_lm_prepare_optimizer
+ from .megatron_lm import prepare_scheduler as megatron_lm_prepare_scheduler
+from .memory import find_executable_batch_size, release_memory
+from .other import (
+ check_os_kernel,
+ clean_state_dict_for_safetensors,
+ compile_regions,
+ compile_regions_deepspeed,
+ convert_bytes,
+ extract_model_from_parallel,
+ get_module_children_bottom_up,
+ get_pretty_name,
+ has_compiled_regions,
+ is_compiled_module,
+ is_port_in_use,
+ load,
+ merge_dicts,
+ model_has_dtensor,
+ recursive_getattr,
+ save,
+ wait_for_everyone,
+ write_basic_config,
+)
+from .random import set_seed, synchronize_rng_state, synchronize_rng_states
+from .torch_xla import install_xla
+from .tqdm import tqdm
+from .transformer_engine import (
+ apply_fp8_autowrap,
+ contextual_fp8_autocast,
+ convert_model,
+ has_transformer_engine_layers,
+)
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/ao.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/ao.py
new file mode 100644
index 0000000000000000000000000000000000000000..73155615b768a01f709bb8e0857617ba58a6ec83
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/ao.py
@@ -0,0 +1,140 @@
+# Copyright 2025 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+Needed utilities for torchao FP8 training.
+"""
+
+from functools import partial
+from typing import TYPE_CHECKING, Callable, Optional
+
+import torch
+
+from .imports import is_torchao_available, torchao_required
+
+
+if TYPE_CHECKING:
+ if is_torchao_available():
+ from torchao.float8.float8_linear import Float8LinearConfig
+
+
+def find_first_last_linear_layers(model: torch.nn.Module):
+ """
+ Finds the first and last linear layer names in a model.
+
+ This is needed during FP8 to avoid issues with instability by keeping the first and last layers unquantized.
+
+ Ref: https://x.com/xariusrke/status/1826669142604141052
+ """
+ first_linear, last_linear = None, None
+ for name, module in model.named_modules():
+ if isinstance(module, torch.nn.Linear):
+ if first_linear is None:
+ first_linear = name
+ last_linear = name
+ return first_linear, last_linear
+
+
+def filter_linear_layers(module, fqn: str, layers_to_filter: list[str]) -> bool:
+ """
+ A function which will check if `module` is:
+ - a `torch.nn.Linear` layer
+ - has in_features and out_features divisible by 16
+ - is not part of `layers_to_filter`
+
+ Args:
+ module (`torch.nn.Module`):
+ The module to check.
+ fqn (`str`):
+ The fully qualified name of the layer.
+ layers_to_filter (`List[str]`):
+ The list of layers to filter.
+ """
+ if isinstance(module, torch.nn.Linear):
+ if module.in_features % 16 != 0 or module.out_features % 16 != 0:
+ return False
+ if fqn in layers_to_filter:
+ return False
+ return True
+
+
+def filter_first_and_last_linear_layers(module, fqn: str) -> bool:
+ """
+ A filter function which will filter out all linear layers except the first and last.
+
+
+
+ For stability reasons, we skip the first and last linear layers Otherwise can lead to the model not training or
+ converging properly
+
+
+
+ Args:
+ module (`torch.nn.Module`):
+ The module to check.
+ fqn (`str`):
+ The fully qualified name of the layer.
+ """
+ first_linear, last_linear = find_first_last_linear_layers(module)
+ return filter_linear_layers(module, fqn, layers_to_filter=[first_linear, last_linear])
+
+
+@torchao_required
+def has_ao_layers(model: torch.nn.Module):
+ from torchao.float8.float8_linear import Float8Linear
+
+ for name, module in model.named_modules():
+ if isinstance(module, Float8Linear):
+ return True
+ return False
+
+
+@torchao_required
+def convert_model_to_fp8_ao(
+ model: torch.nn.Module,
+ config: Optional["Float8LinearConfig"] = None,
+ module_filter_func: Optional[Callable] = filter_first_and_last_linear_layers,
+):
+ """
+ Converts all `nn.Linear` layers in the model (except the first and last) to torchao's `Float8Linear` layer inplace.
+
+ Args:
+ model (`torch.nn.Module`):
+ The model to convert.
+ config (`torchao.float8.Float8LinearConfig`, *optional*):
+ The configuration for the FP8 training. Recommended to utilize
+ `torchao.float8.recipe_name_to_linear_config` to generate this. In general, the default config should be
+ sufficient (what is passed when set to `None`).
+ module_filter_func (`Callable`, *optional*, defaults to `filter_linear_layers`):
+ Optional function that must take in a module and layer name, and returns a boolean indicating whether the
+ module should be converted to FP8. Defaults to `filter_linear_layers`. See it for an example.
+
+ Example:
+
+ ```python
+ from accelerate.utils.ao import convert_model_to_fp8_ao
+
+ model = MyModel()
+ model.to("cuda")
+ convert_to_float8_training(model)
+
+ model.train()
+ ```
+ """
+ from torchao.float8 import convert_to_float8_training
+
+ first_linear, last_linear = find_first_last_linear_layers(model)
+ if module_filter_func is None:
+ module_filter_func = partial(filter_linear_layers, layers_to_filter=[first_linear, last_linear])
+ convert_to_float8_training(model, module_filter_fn=module_filter_func, config=config)
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/bnb.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/bnb.py
new file mode 100644
index 0000000000000000000000000000000000000000..5fbd46eb2f1a3cb07adb2ffb1f15e8f63f26fcff
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/bnb.py
@@ -0,0 +1,469 @@
+# Copyright 2023 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+
+import logging
+import os
+from copy import deepcopy
+from typing import Optional, Union
+
+import torch
+import torch.nn as nn
+
+from accelerate.utils.imports import (
+ is_4bit_bnb_available,
+ is_8bit_bnb_available,
+)
+
+from ..big_modeling import dispatch_model, init_empty_weights
+from .dataclasses import BnbQuantizationConfig
+from .modeling import (
+ find_tied_parameters,
+ get_balanced_memory,
+ infer_auto_device_map,
+ load_checkpoint_in_model,
+ offload_weight,
+ set_module_tensor_to_device,
+)
+
+
+logger = logging.getLogger(__name__)
+
+
+def load_and_quantize_model(
+ model: torch.nn.Module,
+ bnb_quantization_config: BnbQuantizationConfig,
+ weights_location: Optional[Union[str, os.PathLike]] = None,
+ device_map: Optional[dict[str, Union[int, str, torch.device]]] = None,
+ no_split_module_classes: Optional[list[str]] = None,
+ max_memory: Optional[dict[Union[int, str], Union[int, str]]] = None,
+ offload_folder: Optional[Union[str, os.PathLike]] = None,
+ offload_state_dict: bool = False,
+):
+ """
+ This function will quantize the input model with the associated config passed in `bnb_quantization_config`. If the
+ model is in the meta device, we will load and dispatch the weights according to the `device_map` passed. If the
+ model is already loaded, we will quantize the model and put the model on the GPU,
+
+ Args:
+ model (`torch.nn.Module`):
+ Input model. The model can be already loaded or on the meta device
+ bnb_quantization_config (`BnbQuantizationConfig`):
+ The bitsandbytes quantization parameters
+ weights_location (`str` or `os.PathLike`):
+ The folder weights_location to load. It can be:
+ - a path to a file containing a whole model state dict
+ - a path to a `.json` file containing the index to a sharded checkpoint
+ - a path to a folder containing a unique `.index.json` file and the shards of a checkpoint.
+ - a path to a folder containing a unique pytorch_model.bin file.
+ device_map (`Dict[str, Union[int, str, torch.device]]`, *optional*):
+ A map that specifies where each submodule should go. It doesn't need to be refined to each parameter/buffer
+ name, once a given module name is inside, every submodule of it will be sent to the same device.
+ no_split_module_classes (`List[str]`, *optional*):
+ A list of layer class names that should never be split across device (for instance any layer that has a
+ residual connection).
+ max_memory (`Dict`, *optional*):
+ A dictionary device identifier to maximum memory. Will default to the maximum memory available if unset.
+ offload_folder (`str` or `os.PathLike`, *optional*):
+ If the `device_map` contains any value `"disk"`, the folder where we will offload weights.
+ offload_state_dict (`bool`, *optional*, defaults to `False`):
+ If `True`, will temporarily offload the CPU state dict on the hard drive to avoid getting out of CPU RAM if
+ the weight of the CPU state dict + the biggest shard does not fit.
+
+ Returns:
+ `torch.nn.Module`: The quantized model
+ """
+
+ load_in_4bit = bnb_quantization_config.load_in_4bit
+ load_in_8bit = bnb_quantization_config.load_in_8bit
+
+ if load_in_8bit and not is_8bit_bnb_available():
+ raise ImportError(
+ "You have a version of `bitsandbytes` that is not compatible with 8bit quantization,"
+ " make sure you have the latest version of `bitsandbytes` installed."
+ )
+ if load_in_4bit and not is_4bit_bnb_available():
+ raise ValueError(
+ "You have a version of `bitsandbytes` that is not compatible with 4bit quantization,"
+ "make sure you have the latest version of `bitsandbytes` installed."
+ )
+
+ modules_on_cpu = []
+ # custom device map
+ if isinstance(device_map, dict) and len(device_map.keys()) > 1:
+ modules_on_cpu = [key for key, value in device_map.items() if value in ["disk", "cpu"]]
+
+ # We keep some modules such as the lm_head in their original dtype for numerical stability reasons
+ if bnb_quantization_config.skip_modules is None:
+ bnb_quantization_config.skip_modules = get_keys_to_not_convert(model)
+
+ # add cpu modules to skip modules only for 4-bit modules
+ if load_in_4bit:
+ bnb_quantization_config.skip_modules.extend(modules_on_cpu)
+ modules_to_not_convert = bnb_quantization_config.skip_modules
+
+ # We add the modules we want to keep in full precision
+ if bnb_quantization_config.keep_in_fp32_modules is None:
+ bnb_quantization_config.keep_in_fp32_modules = []
+ keep_in_fp32_modules = bnb_quantization_config.keep_in_fp32_modules
+ modules_to_not_convert.extend(keep_in_fp32_modules)
+
+ # compatibility with peft
+ model.is_loaded_in_4bit = load_in_4bit
+ model.is_loaded_in_8bit = load_in_8bit
+
+ model_device = get_parameter_device(model)
+ if model_device.type != "meta":
+ # quantization of an already loaded model
+ logger.warning(
+ "It is not recommended to quantize a loaded model. "
+ "The model should be instantiated under the `init_empty_weights` context manager."
+ )
+ model = replace_with_bnb_layers(model, bnb_quantization_config, modules_to_not_convert=modules_to_not_convert)
+ # convert param to the right dtype
+ dtype = bnb_quantization_config.torch_dtype
+ for name, param in model.state_dict().items():
+ if any(module_to_keep_in_fp32 in name for module_to_keep_in_fp32 in keep_in_fp32_modules):
+ param.to(torch.float32)
+ if param.dtype != torch.float32:
+ name = name.replace(".weight", "").replace(".bias", "")
+ param = getattr(model, name, None)
+ if param is not None:
+ param.to(torch.float32)
+ elif torch.is_floating_point(param):
+ param.to(dtype)
+ if model_device.type == "cuda":
+ model.cuda(torch.cuda.current_device())
+ torch.cuda.empty_cache()
+ elif torch.cuda.is_available():
+ model.to(torch.cuda.current_device())
+ elif torch.xpu.is_available():
+ model.to(torch.xpu.current_device())
+ else:
+ raise RuntimeError("No GPU or Intel XPU found. A GPU or Intel XPU is needed for quantization.")
+ logger.info(
+ f"The model device type is {model_device.type}. However, gpu or intel xpu is needed for quantization."
+ "We move the model to it."
+ )
+ return model
+
+ elif weights_location is None:
+ raise RuntimeError(
+ f"`weights_location` needs to be the folder path containing the weights of the model, but we found {weights_location} "
+ )
+
+ else:
+ with init_empty_weights():
+ model = replace_with_bnb_layers(
+ model, bnb_quantization_config, modules_to_not_convert=modules_to_not_convert
+ )
+ device_map = get_quantized_model_device_map(
+ model,
+ bnb_quantization_config,
+ device_map,
+ max_memory=max_memory,
+ no_split_module_classes=no_split_module_classes,
+ )
+ if offload_state_dict is None and device_map is not None and "disk" in device_map.values():
+ offload_state_dict = True
+
+ offload = any(x in list(device_map.values()) for x in ["cpu", "disk"])
+
+ load_checkpoint_in_model(
+ model,
+ weights_location,
+ device_map,
+ dtype=bnb_quantization_config.torch_dtype,
+ offload_folder=offload_folder,
+ offload_state_dict=offload_state_dict,
+ keep_in_fp32_modules=bnb_quantization_config.keep_in_fp32_modules,
+ offload_8bit_bnb=load_in_8bit and offload,
+ )
+ return dispatch_model(model, device_map=device_map, offload_dir=offload_folder)
+
+
+def get_quantized_model_device_map(
+ model, bnb_quantization_config, device_map=None, max_memory=None, no_split_module_classes=None
+):
+ if device_map is None:
+ if torch.cuda.is_available():
+ device_map = {"": torch.cuda.current_device()}
+ elif torch.xpu.is_available():
+ device_map = {"": torch.xpu.current_device()}
+ else:
+ raise RuntimeError("No GPU found. A GPU is needed for quantization.")
+ logger.info("The device_map was not initialized.Setting device_map to `{'':torch.cuda.current_device()}`.")
+
+ if isinstance(device_map, str):
+ if device_map not in ["auto", "balanced", "balanced_low_0", "sequential"]:
+ raise ValueError(
+ "If passing a string for `device_map`, please choose 'auto', 'balanced', 'balanced_low_0' or "
+ "'sequential'."
+ )
+
+ special_dtypes = {}
+ special_dtypes.update(
+ {
+ name: bnb_quantization_config.torch_dtype
+ for name, _ in model.named_parameters()
+ if any(m in name for m in bnb_quantization_config.skip_modules)
+ }
+ )
+ special_dtypes.update(
+ {
+ name: torch.float32
+ for name, _ in model.named_parameters()
+ if any(m in name for m in bnb_quantization_config.keep_in_fp32_modules)
+ }
+ )
+
+ kwargs = {}
+ kwargs["special_dtypes"] = special_dtypes
+ kwargs["no_split_module_classes"] = no_split_module_classes
+ kwargs["dtype"] = bnb_quantization_config.target_dtype
+
+ # get max_memory for each device.
+ if device_map != "sequential":
+ max_memory = get_balanced_memory(
+ model,
+ low_zero=(device_map == "balanced_low_0"),
+ max_memory=max_memory,
+ **kwargs,
+ )
+
+ kwargs["max_memory"] = max_memory
+ device_map = infer_auto_device_map(model, **kwargs)
+
+ if isinstance(device_map, dict):
+ # check if don't have any quantized module on the cpu
+ modules_not_to_convert = bnb_quantization_config.skip_modules + bnb_quantization_config.keep_in_fp32_modules
+
+ device_map_without_some_modules = {
+ key: device_map[key] for key in device_map.keys() if key not in modules_not_to_convert
+ }
+ for device in ["cpu", "disk"]:
+ if device in device_map_without_some_modules.values():
+ if bnb_quantization_config.load_in_4bit:
+ raise ValueError(
+ """
+ Some modules are dispatched on the CPU or the disk. Make sure you have enough GPU RAM to fit
+ the quantized model. If you want to dispatch the model on the CPU or the disk while keeping
+ these modules in `torch_dtype`, you need to pass a custom `device_map` to
+ `load_and_quantize_model`. Check
+ https://huggingface.co/docs/accelerate/main/en/usage_guides/quantization#offload-modules-to-cpu-and-disk
+ for more details.
+ """
+ )
+ else:
+ logger.info(
+ "Some modules are are offloaded to the CPU or the disk. Note that these modules will be converted to 8-bit"
+ )
+ del device_map_without_some_modules
+ return device_map
+
+
+def replace_with_bnb_layers(model, bnb_quantization_config, modules_to_not_convert=None, current_key_name=None):
+ """
+ A helper function to replace all `torch.nn.Linear` modules by `bnb.nn.Linear8bit` modules or by `bnb.nn.Linear4bit`
+ modules from the `bitsandbytes`library. The function will be run recursively and replace `torch.nn.Linear` modules.
+
+ Parameters:
+ model (`torch.nn.Module`):
+ Input model or `torch.nn.Module` as the function is run recursively.
+ modules_to_not_convert (`List[str]`):
+ Names of the modules to not quantize convert. In practice we keep the `lm_head` in full precision for
+ numerical stability reasons.
+ current_key_name (`List[str]`, *optional*):
+ An array to track the current key of the recursion. This is used to check whether the current key (part of
+ it) is not in the list of modules to not convert.
+ """
+
+ if modules_to_not_convert is None:
+ modules_to_not_convert = []
+
+ model, has_been_replaced = _replace_with_bnb_layers(
+ model, bnb_quantization_config, modules_to_not_convert, current_key_name
+ )
+ if not has_been_replaced:
+ logger.warning(
+ "You are loading your model in 8bit or 4bit but no linear modules were found in your model."
+ " this can happen for some architectures such as gpt2 that uses Conv1D instead of Linear layers."
+ " Please double check your model architecture, or submit an issue on github if you think this is"
+ " a bug."
+ )
+ return model
+
+
+def _replace_with_bnb_layers(
+ model,
+ bnb_quantization_config,
+ modules_to_not_convert=None,
+ current_key_name=None,
+):
+ """
+ Private method that wraps the recursion for module replacement.
+
+ Returns the converted model and a boolean that indicates if the conversion has been successful or not.
+ """
+ # bitsandbytes will initialize CUDA on import, so it needs to be imported lazily
+ import bitsandbytes as bnb
+
+ has_been_replaced = False
+ for name, module in model.named_children():
+ if current_key_name is None:
+ current_key_name = []
+ current_key_name.append(name)
+ if isinstance(module, nn.Linear) and name not in modules_to_not_convert:
+ # Check if the current key is not in the `modules_to_not_convert`
+ current_key_name_str = ".".join(current_key_name)
+ proceed = True
+ for key in modules_to_not_convert:
+ if (
+ (key in current_key_name_str) and (key + "." in current_key_name_str)
+ ) or key == current_key_name_str:
+ proceed = False
+ break
+ if proceed:
+ # Load bnb module with empty weight and replace ``nn.Linear` module
+ if bnb_quantization_config.load_in_8bit:
+ bnb_module = bnb.nn.Linear8bitLt(
+ module.in_features,
+ module.out_features,
+ module.bias is not None,
+ has_fp16_weights=False,
+ threshold=bnb_quantization_config.llm_int8_threshold,
+ )
+ elif bnb_quantization_config.load_in_4bit:
+ bnb_module = bnb.nn.Linear4bit(
+ module.in_features,
+ module.out_features,
+ module.bias is not None,
+ bnb_quantization_config.bnb_4bit_compute_dtype,
+ compress_statistics=bnb_quantization_config.bnb_4bit_use_double_quant,
+ quant_type=bnb_quantization_config.bnb_4bit_quant_type,
+ )
+ else:
+ raise ValueError("load_in_8bit and load_in_4bit can't be both False")
+ bnb_module.weight.data = module.weight.data
+ if module.bias is not None:
+ bnb_module.bias.data = module.bias.data
+ bnb_module.requires_grad_(False)
+ setattr(model, name, bnb_module)
+ has_been_replaced = True
+ if len(list(module.children())) > 0:
+ _, _has_been_replaced = _replace_with_bnb_layers(
+ module, bnb_quantization_config, modules_to_not_convert, current_key_name
+ )
+ has_been_replaced = has_been_replaced | _has_been_replaced
+ # Remove the last key for recursion
+ current_key_name.pop(-1)
+ return model, has_been_replaced
+
+
+def get_keys_to_not_convert(model):
+ r"""
+ An utility function to get the key of the module to keep in full precision if any For example for CausalLM modules
+ we may want to keep the lm_head in full precision for numerical stability reasons. For other architectures, we want
+ to keep the tied weights of the model. The function will return a list of the keys of the modules to not convert in
+ int8.
+
+ Parameters:
+ model (`torch.nn.Module`):
+ Input model
+ """
+ # Create a copy of the model
+ with init_empty_weights():
+ tied_model = deepcopy(model) # this has 0 cost since it is done inside `init_empty_weights` context manager`
+
+ tied_params = find_tied_parameters(tied_model)
+ # For compatibility with Accelerate < 0.18
+ if isinstance(tied_params, dict):
+ tied_keys = sum(list(tied_params.values()), []) + list(tied_params.keys())
+ else:
+ tied_keys = sum(tied_params, [])
+ has_tied_params = len(tied_keys) > 0
+
+ # Check if it is a base model
+ is_base_model = False
+ if hasattr(model, "base_model_prefix"):
+ is_base_model = not hasattr(model, model.base_model_prefix)
+
+ # Ignore this for base models (BertModel, GPT2Model, etc.)
+ if (not has_tied_params) and is_base_model:
+ return []
+
+ # otherwise they have an attached head
+ list_modules = list(model.named_children())
+ list_last_module = [list_modules[-1][0]]
+
+ # add last module together with tied weights
+ intersection = set(list_last_module) - set(tied_keys)
+ list_untouched = list(set(tied_keys)) + list(intersection)
+
+ # remove ".weight" from the keys
+ names_to_remove = [".weight", ".bias"]
+ filtered_module_names = []
+ for name in list_untouched:
+ for name_to_remove in names_to_remove:
+ if name_to_remove in name:
+ name = name.replace(name_to_remove, "")
+ filtered_module_names.append(name)
+
+ return filtered_module_names
+
+
+def has_4bit_bnb_layers(model):
+ """Check if we have `bnb.nn.Linear4bit` or `bnb.nn.Linear8bitLt` layers inside our model"""
+ # bitsandbytes will initialize CUDA on import, so it needs to be imported lazily
+ import bitsandbytes as bnb
+
+ for m in model.modules():
+ if isinstance(m, bnb.nn.Linear4bit):
+ return True
+ return False
+
+
+def get_parameter_device(parameter: nn.Module):
+ return next(parameter.parameters()).device
+
+
+def quantize_and_offload_8bit(model, param, param_name, new_dtype, offload_folder, offload_index, fp16_statistics):
+ # if it is not quantized, we quantize and offload the quantized weights and the SCB stats
+ if fp16_statistics is None:
+ set_module_tensor_to_device(model, param_name, 0, dtype=new_dtype, value=param)
+ tensor_name = param_name
+ module = model
+ if "." in tensor_name:
+ splits = tensor_name.split(".")
+ for split in splits[:-1]:
+ new_module = getattr(module, split)
+ if new_module is None:
+ raise ValueError(f"{module} has no attribute {split}.")
+ module = new_module
+ tensor_name = splits[-1]
+ # offload weights
+ module._parameters[tensor_name].requires_grad = False
+ offload_weight(module._parameters[tensor_name], param_name, offload_folder, index=offload_index)
+ if hasattr(module._parameters[tensor_name], "SCB"):
+ offload_weight(
+ module._parameters[tensor_name].SCB,
+ param_name.replace("weight", "SCB"),
+ offload_folder,
+ index=offload_index,
+ )
+ else:
+ offload_weight(param, param_name, offload_folder, index=offload_index)
+ offload_weight(fp16_statistics, param_name.replace("weight", "SCB"), offload_folder, index=offload_index)
+
+ set_module_tensor_to_device(model, param_name, "meta", dtype=new_dtype, value=torch.empty(*param.size()))
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/constants.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/constants.py
new file mode 100644
index 0000000000000000000000000000000000000000..10a381309f9aed121f8e17e1a7464aa58657a785
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/constants.py
@@ -0,0 +1,106 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import operator as op
+
+import torch
+
+
+SCALER_NAME = "scaler.pt"
+MODEL_NAME = "pytorch_model"
+SAFE_MODEL_NAME = "model"
+RNG_STATE_NAME = "random_states"
+OPTIMIZER_NAME = "optimizer"
+SCHEDULER_NAME = "scheduler"
+SAMPLER_NAME = "sampler"
+PROFILE_PATTERN_NAME = "profile_{suffix}.json"
+WEIGHTS_NAME = f"{MODEL_NAME}.bin"
+WEIGHTS_PATTERN_NAME = "pytorch_model{suffix}.bin"
+WEIGHTS_INDEX_NAME = f"{WEIGHTS_NAME}.index.json"
+SAFE_WEIGHTS_NAME = f"{SAFE_MODEL_NAME}.safetensors"
+SAFE_WEIGHTS_PATTERN_NAME = "model{suffix}.safetensors"
+SAFE_WEIGHTS_INDEX_NAME = f"{SAFE_WEIGHTS_NAME}.index.json"
+SAGEMAKER_PYTORCH_VERSION = "1.10.2"
+SAGEMAKER_PYTHON_VERSION = "py38"
+SAGEMAKER_TRANSFORMERS_VERSION = "4.17.0"
+SAGEMAKER_PARALLEL_EC2_INSTANCES = ["ml.p3.16xlarge", "ml.p3dn.24xlarge", "ml.p4dn.24xlarge"]
+FSDP_SHARDING_STRATEGY = ["FULL_SHARD", "SHARD_GRAD_OP", "NO_SHARD", "HYBRID_SHARD", "HYBRID_SHARD_ZERO2"]
+FSDP_AUTO_WRAP_POLICY = ["TRANSFORMER_BASED_WRAP", "SIZE_BASED_WRAP", "NO_WRAP"]
+FSDP_BACKWARD_PREFETCH = ["BACKWARD_PRE", "BACKWARD_POST", "NO_PREFETCH"]
+FSDP_STATE_DICT_TYPE = ["FULL_STATE_DICT", "LOCAL_STATE_DICT", "SHARDED_STATE_DICT"]
+FSDP2_STATE_DICT_TYPE = ["SHARDED_STATE_DICT", "FULL_STATE_DICT"]
+FSDP_PYTORCH_VERSION = (
+ "2.1.0.a0+32f93b1" # Technically should be 2.1.0, but MS-AMP uses this specific prerelease in their Docker image.
+)
+FSDP2_PYTORCH_VERSION = "2.6.0"
+FSDP_MODEL_NAME = "pytorch_model_fsdp"
+DEEPSPEED_MULTINODE_LAUNCHERS = ["pdsh", "standard", "openmpi", "mvapich", "mpich", "nossh", "slurm"]
+TORCH_DYNAMO_MODES = ["default", "reduce-overhead", "max-autotune"]
+ELASTIC_LOG_LINE_PREFIX_TEMPLATE_PYTORCH_VERSION = "2.2.0"
+XPU_PROFILING_AVAILABLE_PYTORCH_VERSION = "2.4.0"
+MITA_PROFILING_AVAILABLE_PYTORCH_VERSION = "2.1.0"
+BETA_TP_AVAILABLE_PYTORCH_VERSION = "2.3.0"
+
+BETA_TP_AVAILABLE_TRANSFORMERS_VERSION = "4.52.0"
+BETA_CP_AVAILABLE_PYTORCH_VERSION = "2.6.0"
+BETA_SP_AVAILABLE_DEEPSPEED_VERSION = "0.18.2"
+
+STR_OPERATION_TO_FUNC = {">": op.gt, ">=": op.ge, "==": op.eq, "!=": op.ne, "<=": op.le, "<": op.lt}
+
+# These are the args for `torch.distributed.launch` for pytorch < 1.9
+TORCH_LAUNCH_PARAMS = [
+ "nnodes",
+ "nproc_per_node",
+ "rdzv_backend",
+ "rdzv_endpoint",
+ "rdzv_id",
+ "rdzv_conf",
+ "standalone",
+ "max_restarts",
+ "monitor_interval",
+ "start_method",
+ "role",
+ "module",
+ "m",
+ "no_python",
+ "run_path",
+ "log_dir",
+ "r",
+ "redirects",
+ "t",
+ "tee",
+ "node_rank",
+ "master_addr",
+ "master_port",
+]
+
+CUDA_DISTRIBUTED_TYPES = ["DEEPSPEED", "MULTI_GPU", "FSDP", "MEGATRON_LM", "TP"]
+TORCH_DISTRIBUTED_OPERATION_TYPES = CUDA_DISTRIBUTED_TYPES + [
+ "MULTI_NPU",
+ "MULTI_MLU",
+ "MULTI_SDAA",
+ "MULTI_MUSA",
+ "MULTI_XPU",
+ "MULTI_CPU",
+ "MULTI_HPU",
+]
+SUPPORTED_PYTORCH_LAYERS_FOR_UPCASTING = (
+ torch.nn.Conv1d,
+ torch.nn.Conv2d,
+ torch.nn.Conv3d,
+ torch.nn.ConvTranspose1d,
+ torch.nn.ConvTranspose2d,
+ torch.nn.ConvTranspose3d,
+ torch.nn.Linear,
+)
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/dataclasses.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/dataclasses.py
new file mode 100644
index 0000000000000000000000000000000000000000..b226c25d312fe18022714dcd9af8ac7a90ab2775
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/dataclasses.py
@@ -0,0 +1,2985 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+General namespace and dataclass related classes
+"""
+
+import argparse
+import copy
+import enum
+import functools
+import logging
+import os
+import warnings
+from collections.abc import Iterable
+from contextlib import contextmanager
+from dataclasses import dataclass, field
+from datetime import timedelta
+from typing import TYPE_CHECKING, Any, Callable, Literal, Optional, Union, get_args
+
+import torch
+
+from .constants import (
+ BETA_CP_AVAILABLE_PYTORCH_VERSION,
+ BETA_TP_AVAILABLE_PYTORCH_VERSION,
+ BETA_TP_AVAILABLE_TRANSFORMERS_VERSION,
+ FSDP2_PYTORCH_VERSION,
+ FSDP_AUTO_WRAP_POLICY,
+ FSDP_BACKWARD_PREFETCH,
+ FSDP_SHARDING_STRATEGY,
+ MITA_PROFILING_AVAILABLE_PYTORCH_VERSION,
+ XPU_PROFILING_AVAILABLE_PYTORCH_VERSION,
+)
+from .environment import parse_flag_from_env, str_to_bool
+from .imports import (
+ is_cuda_available,
+ is_hpu_available,
+ is_mlu_available,
+ is_msamp_available,
+ is_musa_available,
+ is_npu_available,
+ is_transformer_engine_available,
+ is_xpu_available,
+)
+from .versions import compare_versions, is_torch_version
+
+
+if TYPE_CHECKING:
+ # Mock imports for type checking
+ from torchao.float8 import Float8LinearConfig
+
+
+logger = logging.getLogger(__name__)
+
+
+class KwargsHandler:
+ """
+ Internal mixin that implements a `to_kwargs()` method for a dataclass.
+ """
+
+ def to_dict(self):
+ return copy.deepcopy(self.__dict__)
+
+ def to_kwargs(self):
+ """
+ Returns a dictionary containing the attributes with values different from the default of this class.
+ """
+ # import clear_environment here to avoid circular import problem
+ from .environment import clear_environment
+
+ with clear_environment():
+ default_dict = self.__class__().to_dict()
+ this_dict = self.to_dict()
+ return {k: v for k, v in this_dict.items() if default_dict[k] != v}
+
+
+class EnumWithContains(enum.EnumMeta):
+ "A metaclass that adds the ability to check if `self` contains an item with the `in` operator"
+
+ def __contains__(cls, item):
+ try:
+ cls(item)
+ except ValueError:
+ return False
+ return True
+
+
+class BaseEnum(enum.Enum, metaclass=EnumWithContains):
+ "An enum class that can get the value of an item with `str(Enum.key)`"
+
+ def __str__(self):
+ return self.value
+
+ @classmethod
+ def list(cls):
+ "Method to list all the possible items in `cls`"
+ return list(map(str, cls))
+
+
+@dataclass
+class AutocastKwargs(KwargsHandler):
+ """
+ Use this object in your [`Accelerator`] to customize how `torch.autocast` behaves. Please refer to the
+ documentation of this [context manager](https://pytorch.org/docs/stable/amp.html#torch.autocast) for more
+ information on each argument.
+
+ Example:
+
+ ```python
+ from accelerate import Accelerator
+ from accelerate.utils import AutocastKwargs
+
+ kwargs = AutocastKwargs(cache_enabled=True)
+ accelerator = Accelerator(kwargs_handlers=[kwargs])
+ ```
+ """
+
+ enabled: bool = True
+ cache_enabled: Optional[bool] = None
+
+
+class DDPCommunicationHookType(BaseEnum):
+ """
+ Represents a type of communication hook used in DDP.
+
+ Values:
+
+ - **NO** -- no communication hook
+ - **FP16** -- DDP communication hook to compress the gradients in FP16
+ - **BF16** -- DDP communication hook to compress the gradients in BF16
+ - **POWER_SGD** -- DDP communication hook to use PowerSGD
+ - **BATCHED_POWER_SGD** -- DDP communication hook to use batched PowerSGD
+ """
+
+ NO = "no"
+ FP16 = "fp16"
+ BF16 = "bf16"
+ POWER_SGD = "power_sgd"
+ BATCHED_POWER_SGD = "batched_power_sgd"
+
+
+@dataclass
+class DistributedDataParallelKwargs(KwargsHandler):
+ """
+ Use this object in your [`Accelerator`] to customize how your model is wrapped in a
+ `torch.nn.parallel.DistributedDataParallel`. Please refer to the documentation of this
+ [wrapper](https://pytorch.org/docs/stable/generated/torch.nn.parallel.DistributedDataParallel.html) for more
+ information on each argument.
+
+
+
+ `gradient_as_bucket_view` is only available in PyTorch 1.7.0 and later versions.
+
+ `static_graph` is only available in PyTorch 1.11.0 and later versions.
+
+
+
+ Example:
+
+ ```python
+ from accelerate import Accelerator
+ from accelerate.utils import DistributedDataParallelKwargs
+
+ kwargs = DistributedDataParallelKwargs(find_unused_parameters=True)
+ accelerator = Accelerator(kwargs_handlers=[kwargs])
+ ```
+ """
+
+ dim: int = 0
+ broadcast_buffers: bool = True
+ bucket_cap_mb: int = 25
+ find_unused_parameters: bool = False
+ check_reduction: bool = False
+ gradient_as_bucket_view: bool = False
+ static_graph: bool = False
+
+ comm_hook: DDPCommunicationHookType = DDPCommunicationHookType.NO
+ comm_wrapper: Literal[
+ DDPCommunicationHookType.NO,
+ DDPCommunicationHookType.FP16,
+ DDPCommunicationHookType.BF16,
+ ] = DDPCommunicationHookType.NO
+ comm_state_option: dict = field(default_factory=dict)
+
+ def to_dict(self, ignore_keys=("comm_hook", "comm_wrapper", "comm_state_option")):
+ return {k: v for k, v in super().to_dict().items() if k not in ignore_keys}
+
+ def register_comm_hook(self, model):
+ from torch.distributed.algorithms.ddp_comm_hooks import (
+ default_hooks,
+ powerSGD_hook,
+ )
+
+ hook_map: dict[DDPCommunicationHookType, Callable] = {
+ DDPCommunicationHookType.FP16: default_hooks.fp16_compress_hook,
+ DDPCommunicationHookType.BF16: default_hooks.bf16_compress_hook,
+ DDPCommunicationHookType.POWER_SGD: powerSGD_hook.powerSGD_hook,
+ DDPCommunicationHookType.BATCHED_POWER_SGD: powerSGD_hook.batched_powerSGD_hook,
+ }
+
+ wrapper_map: dict[DDPCommunicationHookType, Callable] = {
+ DDPCommunicationHookType.FP16: default_hooks.fp16_compress_wrapper,
+ DDPCommunicationHookType.BF16: default_hooks.bf16_compress_wrapper,
+ }
+
+ hook: Optional[Callable] = hook_map.get(self.comm_hook)
+ wrapper: Optional[Callable] = wrapper_map.get(self.comm_wrapper)
+
+ if hook and wrapper:
+ hook = wrapper(hook)
+
+ if hook:
+ state = (
+ powerSGD_hook.PowerSGDState(None, **self.comm_state_option)
+ if self.comm_hook
+ in (
+ DDPCommunicationHookType.POWER_SGD,
+ DDPCommunicationHookType.BATCHED_POWER_SGD,
+ )
+ else None
+ )
+ model.register_comm_hook(
+ state=state,
+ hook=hook,
+ )
+
+
+@dataclass
+class GradScalerKwargs(KwargsHandler):
+ """
+ Use this object in your [`Accelerator`] to customize the behavior of mixed precision, specifically how the
+ `torch.amp.GradScaler` or `torch.cuda.amp.GradScaler` used is created. Please refer to the documentation of this
+ [scaler](https://pytorch.org/docs/stable/amp.html?highlight=gradscaler) for more information on each argument.
+
+
+
+ `torch.cuda.amp.GradScaler` is only available in PyTorch 1.5.0 and later versions, and `torch.amp.GradScaler` is
+ only available in PyTorch 2.4.0 and later versions.
+
+
+
+ Example:
+
+ ```python
+ from accelerate import Accelerator
+ from accelerate.utils import GradScalerKwargs
+
+ kwargs = GradScalerKwargs(backoff_factor=0.25)
+ accelerator = Accelerator(kwargs_handlers=[kwargs])
+ ```
+ """
+
+ init_scale: float = 65536.0
+ growth_factor: float = 2.0
+ backoff_factor: float = 0.5
+ growth_interval: int = 2000
+ enabled: bool = True
+
+
+@dataclass
+class InitProcessGroupKwargs(KwargsHandler):
+ """
+ Use this object in your [`Accelerator`] to customize the initialization of the distributed processes. Please refer
+ to the documentation of this
+ [method](https://pytorch.org/docs/stable/distributed.html#torch.distributed.init_process_group) for more
+ information on each argument.
+
+ Note: If `timeout` is set to `None`, the default will be based upon how `backend` is set.
+
+ ```python
+ from datetime import timedelta
+ from accelerate import Accelerator
+ from accelerate.utils import InitProcessGroupKwargs
+
+ kwargs = InitProcessGroupKwargs(timeout=timedelta(seconds=800))
+ accelerator = Accelerator(kwargs_handlers=[kwargs])
+ ```
+ """
+
+ backend: Optional[str] = "nccl"
+ init_method: Optional[str] = None
+ timeout: Optional[timedelta] = None
+
+ def __post_init__(self):
+ if self.timeout is None:
+ seconds = 1800 if self.backend != "nccl" else 600
+ self.timeout = timedelta(seconds=seconds)
+
+
+# Literals
+Backend = Literal["MSAMP", "TE"]
+OptLevel = Literal["O1", "O2"]
+FP8Format = Literal["HYBRID", "E4M3", "E5M2"]
+AmaxComputeAlgorithm = Literal["max", "most_recent"]
+
+
+# FP8 training recipe kwargs
+@dataclass
+class AORecipeKwargs(KwargsHandler):
+ """
+ Use this object in your [`Accelerator`] to customize the initialization of the recipe for FP8 mixed precision
+ training with `torchao` FP8.
+
+ Args:
+ config (`torchao.float8.Float8LinearConfig`, *optional*, default to `None`):
+ The configuration for the FP8 training. In general, the default config should be sufficient.
+ module_filter_func (`Callable`, *optional*, default to `None`):
+ Optional function that must take in a module and layer name, and returns a boolean indicating whether the
+ module should be converted to FP8. Defaults to `accelerate.utils.ao.filter_linear_layers`. See it for an
+ example.
+ """
+
+ config: Optional["Float8LinearConfig"] = None
+ module_filter_func: Optional[Callable] = None
+
+
+@dataclass
+class TERecipeKwargs(KwargsHandler):
+ """
+ Use this object in your [`Accelerator`] to customize the initialization of the recipe for FP8 mixed precision
+ training with `transformer-engine`.
+
+
+
+ For more information on the args, please refer to the API
+ [documentation](https://docs.nvidia.com/deeplearning/transformer-engine/user-guide/api/common.html).
+
+
+
+ ```python
+ from accelerate import Accelerator
+ from accelerate.utils import TERecipeKwargs
+
+ kwargs = TERecipeKwargs(fp8_format="HYBRID")
+ accelerator = Accelerator(mixed_precision="fp8", kwargs_handlers=[kwargs])
+ ```
+
+ Args:
+ use_autocast_during_eval (`bool`, *optional*, default to `False`):
+ Whether to use FP8 autocast during eval mode. Generally better metrics are found when this is `False`.
+ margin (`int`, *optional*, default to 0):
+ The margin to use for the gradient scaling.
+ interval (`int`, *optional*, default to 1):
+ The interval to use for how often the scaling factor is recomputed.
+ fp8_format (`str`, *optional*, default to "HYBRID"):
+ The format to use for the FP8 recipe. Must be one of `HYBRID`, `E4M3` or `E5M2`. (Generally `HYBRID` for
+ training, `E4M3` or `E5M2` for evaluation)
+ amax_history_len (`int`, *optional*, default to 1024):
+ The length of the history to use for the scaling factor computation
+ amax_compute_algo (`str`, *optional*, default to "most_recent"):
+ The algorithm to use for the scaling factor computation. Must be one of `max` or `most_recent`.
+ override_linear_precision (`tuple` of three `bool`, *optional*, default to `(False, False, False)`):
+ Whether or not to execute `fprop`, `dgrad`, and `wgrad` GEMMS in higher precision.
+ """
+
+ use_autocast_during_eval: Optional[bool] = None
+ margin: Optional[int] = None
+ interval: Optional[int] = None
+ fp8_format: FP8Format = None
+ amax_history_len: Optional[int] = None
+ amax_compute_algo: AmaxComputeAlgorithm = None
+ override_linear_precision: tuple[bool, bool, bool] = None
+ use_mxfp8_block_scaling: Optional[bool] = None
+
+ def __post_init__(self):
+ env_prefix = "ACCELERATE_FP8_"
+ if not is_transformer_engine_available():
+ raise ImportError("TransformerEngine is not available. Please install it or use a different backend.")
+ if self.use_autocast_during_eval is None:
+ self.use_autocast_during_eval = parse_flag_from_env(env_prefix + "USE_AUTOCAST_DURING_EVAL")
+ if self.margin is None:
+ self.margin = int(os.environ.get(env_prefix + "MARGIN", 0))
+ if self.interval is None:
+ self.interval = int(os.environ.get(env_prefix + "INTERVAL", 1))
+ if self.fp8_format is None:
+ self.fp8_format = os.environ.get(env_prefix + "FORMAT", "HYBRID")
+ self.fp8_format = self.fp8_format.upper()
+ if self.fp8_format not in get_args(FP8Format):
+ raise ValueError(f"`fp8_format` must be one of {' or '.join(get_args(FP8Format))}.")
+ if self.amax_compute_algo is None:
+ self.amax_compute_algo = os.environ.get(env_prefix + "AMAX_COMPUTE_ALGO", "most_recent")
+ self.amax_compute_algo = self.amax_compute_algo.lower()
+ if self.amax_compute_algo not in get_args(AmaxComputeAlgorithm):
+ raise ValueError(f"`amax_compute_algo` must be one of {' or '.join(get_args(AmaxComputeAlgorithm))}")
+ if self.amax_history_len is None:
+ self.amax_history_len = int(os.environ.get(env_prefix + "AMAX_HISTORY_LEN", 1024))
+ if self.override_linear_precision is None:
+ fprop = parse_flag_from_env(env_prefix + "OVERRIDE_FPROP")
+ dgrad = parse_flag_from_env(env_prefix + "OVERRIDE_DGRAD")
+ wgrad = parse_flag_from_env(env_prefix + "OVERRIDE_WGRAD")
+ self.override_linear_precision = (fprop, dgrad, wgrad)
+ if self.use_mxfp8_block_scaling is None:
+ self.use_mxfp8_block_scaling = parse_flag_from_env(env_prefix + "USE_MXFP8_BLOCK_SCALING")
+
+
+@dataclass
+class MSAMPRecipeKwargs(KwargsHandler):
+ """
+ Use this object in your [`Accelerator`] to customize the initialization of the recipe for FP8 mixed precision
+ training with `ms-amp`.
+ """
+
+ opt_level: OptLevel = None
+
+ def __post_init__(self):
+ env_prefix = "ACCELERATE_FP8_"
+ if self.opt_level is None:
+ self.opt_level = os.environ.get(env_prefix + "OPT_LEVEL", "O2")
+ if self.opt_level not in get_args(OptLevel):
+ raise ValueError(f"`opt_level` must be one of {' or '.join(get_args(OptLevel))}")
+
+
+@dataclass
+class FP8RecipeKwargs(TERecipeKwargs, MSAMPRecipeKwargs):
+ """
+ Deprecated. Please use one of the proper FP8 recipe kwargs classes such as `TERecipeKwargs` or `MSAMPRecipeKwargs`
+ instead.
+ """
+
+ backend: Backend = None
+
+ def __post_init__(self):
+ env_prefix = "ACCELERATE_FP8_"
+ warnings.warn(
+ "FP8RecipeKwargs is deprecated and will be removed in Accelerate v2.0.0. "
+ "Please use one of the proper FP8 recipe kwargs classes such as TERecipeKwargs or MSAMPRecipeKwargs instead.",
+ FutureWarning,
+ )
+ default_backend = "msamp" if is_msamp_available() else "te"
+ if self.backend is None:
+ self.backend = os.environ.get(env_prefix + "BACKEND", default_backend)
+ self.backend = self.backend.upper()
+ if self.backend not in get_args(Backend):
+ raise ValueError("`backend` must be 'MSAMP' or 'TE' (TransformerEngine) to use `FP8RecipeKwargs`.")
+ super().__post_init__()
+
+
+# Literal
+ProfilerActivity = Literal["cpu", "xpu", "mtia", "cuda", "hpu"]
+
+
+@dataclass
+class ProfileKwargs(KwargsHandler):
+ """
+ Use this object in your [`Accelerator`] to customize the initialization of the profiler. Please refer to the
+ documentation of this [context manager](https://pytorch.org/docs/stable/profiler.html#torch.profiler.profile) for
+ more information on each argument.
+
+
+
+ `torch.profiler` is only available in PyTorch 1.8.1 and later versions.
+
+
+
+ Example:
+
+ ```python
+ from accelerate import Accelerator
+ from accelerate.utils import ProfileKwargs
+
+ kwargs = ProfileKwargs(activities=["cpu", "cuda"])
+ accelerator = Accelerator(kwargs_handlers=[kwargs])
+ ```
+
+ Args:
+ activities (`List[str]`, *optional*, default to `None`):
+ The list of activity groups to use in profiling. Must be one of `"cpu"`, `"xpu"`, `"mtia"`, "hpu" or
+ `"cuda"`.
+ schedule_option (`Dict[str, int]`, *optional*, default to `None`):
+ The schedule option to use for the profiler. Available keys are `wait`, `warmup`, `active`, `repeat` and
+ `skip_first`. The profiler will skip the first `skip_first` steps, then wait for `wait` steps, then do the
+ warmup for the next `warmup` steps, then do the active recording for the next `active` steps and then
+ repeat the cycle starting with `wait` steps. The optional number of cycles is specified with the `repeat`
+ parameter, the zero value means that the cycles will continue until the profiling is finished.
+ on_trace_ready (`Callable`, *optional*, default to `None`):
+ Callable that is called at each step when schedule returns `ProfilerAction.RECORD_AND_SAVE` during the
+ profiling.
+ record_shapes (`bool`, *optional*, default to `False`):
+ Save information about operator’s input shapes.
+ profile_memory (`bool`, *optional*, default to `False`):
+ Track tensor memory allocation/deallocation
+ with_stack (`bool`, *optional*, default to `False`):
+ Record source information (file and line number) for the ops.
+ with_flops (`bool`, *optional*, default to `False`):
+ Use formula to estimate the FLOPS of specific operators
+ with_modules (`bool`, *optional*, default to `False`):
+ Record module hierarchy (including function names) corresponding to the callstack of the op.
+ output_trace_dir (`str`, *optional*, default to `None`):
+ Exports the collected trace in Chrome JSON format. Chrome use 'chrome://tracing' view json file. Defaults
+ to None, which means profiling does not store json files.
+ """
+
+ activities: Optional[list[ProfilerActivity]] = None
+ schedule_option: Optional[dict[str, int]] = None
+ on_trace_ready: Optional[Callable] = None
+ record_shapes: bool = False
+ profile_memory: bool = False
+ with_stack: bool = False
+ with_flops: bool = False
+ with_modules: bool = False
+ output_trace_dir: Optional[str] = None
+
+ def _get_profiler_activity(self, activity: ProfilerActivity) -> torch.profiler.ProfilerActivity:
+ """Get the profiler activity from the string.
+
+ Args:
+ activity (str): The profiler activity name.
+
+ Returns:
+ torch.profiler.ProfilerActivity: The profiler activity.
+ """
+
+ profiler_activity_map: dict[str, torch.profiler.ProfilerActivity] = {
+ "cpu": torch.profiler.ProfilerActivity.CPU,
+ "cuda": torch.profiler.ProfilerActivity.CUDA,
+ }
+
+ if is_hpu_available():
+ profiler_activity_map["hpu"] = torch.profiler.ProfilerActivity.HPU
+
+ if is_torch_version(">=", XPU_PROFILING_AVAILABLE_PYTORCH_VERSION):
+ if torch.xpu.is_available():
+ profiler_activity_map["xpu"] = torch.profiler.ProfilerActivity.XPU
+
+ if is_torch_version(">=", MITA_PROFILING_AVAILABLE_PYTORCH_VERSION):
+ if torch.mtia.is_available():
+ profiler_activity_map["mtia"] = torch.profiler.ProfilerActivity.MTIA
+
+ if activity not in profiler_activity_map:
+ raise ValueError(f"Invalid profiler activity: {activity}. Must be one of {list(profiler_activity_map)}.")
+ return profiler_activity_map[activity]
+
+ def build(self) -> torch.profiler.profile:
+ """
+ Build a profiler object with the current configuration.
+
+ Returns:
+ torch.profiler.profile: The profiler object.
+ """
+ activities: Optional[list[ProfilerActivity]] = None
+ if self.activities is not None:
+ activities = [self._get_profiler_activity(activity) for activity in self.activities]
+ schedule: Optional[torch.profiler.schedule] = None
+ if self.schedule_option is not None:
+ schedule = torch.profiler.schedule(**self.schedule_option)
+
+ return torch.profiler.profile(
+ activities=activities,
+ schedule=schedule,
+ on_trace_ready=self.on_trace_ready,
+ record_shapes=self.record_shapes,
+ profile_memory=self.profile_memory,
+ with_stack=self.with_stack,
+ with_flops=self.with_flops,
+ with_modules=self.with_modules,
+ )
+
+
+class DistributedType(str, enum.Enum):
+ """
+ Represents a type of distributed environment.
+
+ Values:
+
+ - **NO** -- Not a distributed environment, just a single process.
+ - **MULTI_CPU** -- Distributed on multiple CPU nodes.
+ - **MULTI_GPU** -- Distributed on multiple GPUs.
+ - **MULTI_MLU** -- Distributed on multiple MLUs.
+ - **MULTI_SDAA** -- Distributed on multiple SDAAs.
+ - **MULTI_MUSA** -- Distributed on multiple MUSAs.
+ - **MULTI_NPU** -- Distributed on multiple NPUs.
+ - **MULTI_XPU** -- Distributed on multiple XPUs.
+ - **MULTI_HPU** -- Distributed on multiple HPUs.
+ - **DEEPSPEED** -- Using DeepSpeed.
+ - **XLA** -- Using TorchXLA.
+ """
+
+ # Subclassing str as well as Enum allows the `DistributedType` to be JSON-serializable out of the box.
+ NO = "NO"
+ MULTI_CPU = "MULTI_CPU"
+ MULTI_GPU = "MULTI_GPU"
+ MULTI_NPU = "MULTI_NPU"
+ MULTI_MLU = "MULTI_MLU"
+ MULTI_SDAA = "MULTI_SDAA"
+ MULTI_MUSA = "MULTI_MUSA"
+ MULTI_XPU = "MULTI_XPU"
+ DEEPSPEED = "DEEPSPEED"
+ FSDP = "FSDP"
+ XLA = "XLA"
+ MEGATRON_LM = "MEGATRON_LM"
+ MULTI_HPU = "MULTI_HPU"
+
+
+class SageMakerDistributedType(str, enum.Enum):
+ """
+ Represents a type of distributed environment.
+
+ Values:
+
+ - **NO** -- Not a distributed environment, just a single process.
+ - **DATA_PARALLEL** -- using sagemaker distributed data parallelism.
+ - **MODEL_PARALLEL** -- using sagemaker distributed model parallelism.
+ """
+
+ # Subclassing str as well as Enum allows the `SageMakerDistributedType` to be JSON-serializable out of the box.
+ NO = "NO"
+ DATA_PARALLEL = "DATA_PARALLEL"
+ MODEL_PARALLEL = "MODEL_PARALLEL"
+
+
+class FP8BackendType(str, enum.Enum):
+ """
+ Represents the backend used for FP8.
+
+ Values:
+
+ - **TE** -- using TransformerEngine.
+ - **MSAMP** -- using msamp.
+ """
+
+ # Subclassing str as well as Enum allows the `FP8BackendType` to be JSON-serializable out of the box.
+ NO = "NO"
+ TE = "TE"
+ MSAMP = "MSAMP"
+ AO = "AO"
+
+
+class ComputeEnvironment(str, enum.Enum):
+ """
+ Represents a type of the compute environment.
+
+ Values:
+
+ - **LOCAL_MACHINE** -- private/custom cluster hardware.
+ - **AMAZON_SAGEMAKER** -- Amazon SageMaker as compute environment.
+ """
+
+ # Subclassing str as well as Enum allows the `ComputeEnvironment` to be JSON-serializable out of the box.
+ LOCAL_MACHINE = "LOCAL_MACHINE"
+ AMAZON_SAGEMAKER = "AMAZON_SAGEMAKER"
+
+
+class DynamoBackend(str, BaseEnum):
+ """
+ Represents a dynamo backend (see https://pytorch.org/docs/stable/torch.compiler.html).
+
+ Values:
+
+ - **NO** -- Do not use torch dynamo.
+ - **EAGER** -- Uses PyTorch to run the extracted GraphModule. This is quite useful in debugging TorchDynamo
+ issues.
+ - **AOT_EAGER** -- Uses AotAutograd with no compiler, i.e, just using PyTorch eager for the AotAutograd's
+ extracted forward and backward graphs. This is useful for debugging, and unlikely to give speedups.
+ - **INDUCTOR** -- Uses TorchInductor backend with AotAutograd and cudagraphs by leveraging codegened Triton
+ kernels. [Read
+ more](https://dev-discuss.pytorch.org/t/torchinductor-a-pytorch-native-compiler-with-define-by-run-ir-and-symbolic-shapes/747)
+ - **AOT_TS_NVFUSER** -- nvFuser with AotAutograd/TorchScript. [Read
+ more](https://dev-discuss.pytorch.org/t/tracing-with-primitives-update-1-nvfuser-and-its-primitives/593)
+ - **NVPRIMS_NVFUSER** -- nvFuser with PrimTorch. [Read
+ more](https://dev-discuss.pytorch.org/t/tracing-with-primitives-update-1-nvfuser-and-its-primitives/593)
+ - **CUDAGRAPHS** -- cudagraphs with AotAutograd. [Read more](https://github.com/pytorch/torchdynamo/pull/757)
+ - **OFI** -- Uses Torchscript optimize_for_inference. Inference only. [Read
+ more](https://pytorch.org/docs/stable/generated/torch.jit.optimize_for_inference.html)
+ - **FX2TRT** -- Uses Nvidia TensorRT for inference optimizations. Inference only. [Read
+ more](https://github.com/pytorch/TensorRT/blob/master/docsrc/tutorials/getting_started_with_fx_path.rst)
+ - **ONNXRT** -- Uses ONNXRT for inference on CPU/GPU. Inference only. [Read more](https://onnxruntime.ai/)
+ - **TENSORRT** -- Uses ONNXRT to run TensorRT for inference optimizations. [Read
+ more](https://github.com/onnx/onnx-tensorrt)
+ - **AOT_TORCHXLA_TRACE_ONCE** -- Uses Pytorch/XLA with TorchDynamo optimization, for training. [Read
+ more](https://github.com/pytorch/xla/blob/r2.0/docs/dynamo.md)
+ - **TORCHXLA_TRACE_ONCE** -- Uses Pytorch/XLA with TorchDynamo optimization, for inference. [Read
+ more](https://github.com/pytorch/xla/blob/r2.0/docs/dynamo.md)
+ - **IPEX** -- Uses IPEX for inference on CPU. Inference only. [Read
+ more](https://github.com/intel/intel-extension-for-pytorch).
+ - **TVM** -- Uses Apache TVM for inference optimizations. [Read more](https://tvm.apache.org/)
+ - **HPU_BACKEND** -- Uses HPU backend for inference optimizations.
+
+ """
+
+ # Subclassing str as well as Enum allows the `SageMakerDistributedType` to be JSON-serializable out of the box.
+ NO = "NO"
+ EAGER = "EAGER"
+ AOT_EAGER = "AOT_EAGER"
+ INDUCTOR = "INDUCTOR"
+ AOT_TS_NVFUSER = "AOT_TS_NVFUSER"
+ NVPRIMS_NVFUSER = "NVPRIMS_NVFUSER"
+ CUDAGRAPHS = "CUDAGRAPHS"
+ OFI = "OFI"
+ FX2TRT = "FX2TRT"
+ ONNXRT = "ONNXRT"
+ TENSORRT = "TENSORRT"
+ AOT_TORCHXLA_TRACE_ONCE = "AOT_TORCHXLA_TRACE_ONCE"
+ TORCHXLA_TRACE_ONCE = "TORCHXLA_TRACE_ONCE"
+ IPEX = "IPEX"
+ TVM = "TVM"
+ HPU_BACKEND = "HPU_BACKEND"
+
+
+class LoggerType(BaseEnum):
+ """Represents a type of supported experiment tracker
+
+ Values:
+
+ - **ALL** -- all available trackers in the environment that are supported
+ - **TENSORBOARD** -- TensorBoard as an experiment tracker
+ - **WANDB** -- wandb as an experiment tracker
+ - **TRACKIO** -- trackio as an experiment tracker
+ - **COMETML** -- comet_ml as an experiment tracker
+ - **MLFLOW** -- mlflow as an experiment tracker
+ - **CLEARML** -- clearml as an experiment tracker
+ - **DVCLIVE** -- dvclive as an experiment tracker
+ - **SWANLAB** -- swanlab as an experiment tracker
+ """
+
+ ALL = "all"
+ AIM = "aim"
+ TENSORBOARD = "tensorboard"
+ WANDB = "wandb"
+ TRACKIO = "trackio"
+ COMETML = "comet_ml"
+ MLFLOW = "mlflow"
+ CLEARML = "clearml"
+ DVCLIVE = "dvclive"
+ SWANLAB = "swanlab"
+
+
+class PrecisionType(str, BaseEnum):
+ """Represents a type of precision used on floating point values
+
+ Values:
+
+ - **NO** -- using full precision (FP32)
+ - **FP16** -- using half precision
+ - **BF16** -- using brain floating point precision
+ """
+
+ NO = "no"
+ FP8 = "fp8"
+ FP16 = "fp16"
+ BF16 = "bf16"
+
+
+class RNGType(BaseEnum):
+ TORCH = "torch"
+ CUDA = "cuda"
+ MLU = "mlu"
+ SDAA = "sdaa"
+ MUSA = "musa"
+ NPU = "npu"
+ XLA = "xla"
+ XPU = "xpu"
+ HPU = "hpu"
+ GENERATOR = "generator"
+
+
+class CustomDtype(enum.Enum):
+ r"""
+ An enum that contains multiple custom dtypes that can be used for `infer_auto_device_map`.
+ """
+
+ FP8 = "fp8"
+ INT4 = "int4"
+ INT2 = "int2"
+
+
+# data classes
+
+
+@dataclass
+class TensorInformation:
+ shape: torch.Size
+ dtype: torch.dtype
+
+
+@dataclass
+class DataLoaderConfiguration:
+ """
+ Configuration for dataloader-related items when calling `accelerator.prepare`.
+
+ Args:
+ split_batches (`bool`, defaults to `False`):
+ Whether or not the accelerator should split the batches yielded by the dataloaders across the devices. If
+ `True`, the actual batch size used will be the same on any kind of distributed processes, but it must be a
+ round multiple of `num_processes` you are using. If `False`, actual batch size used will be the one set in
+ your script multiplied by the number of processes.
+ dispatch_batches (`bool`, defaults to `None`):
+ If set to `True`, the dataloader prepared by the Accelerator is only iterated through on the main process
+ and then the batches are split and broadcast to each process. Will default to `True` for `DataLoader` whose
+ underlying dataset is an `IterableDataset`, `False` otherwise.
+ even_batches (`bool`, defaults to `True`):
+ If set to `True`, in cases where the total batch size across all processes does not exactly divide the
+ dataset, samples at the start of the dataset will be duplicated so the batch can be divided equally among
+ all workers.
+ use_seedable_sampler (`bool`, defaults to `False`):
+ Whether or not use a fully seedable random sampler ([`data_loader.SeedableRandomSampler`]). Ensures
+ training results are fully reproducible using a different sampling technique. While seed-to-seed results
+ may differ, on average the differences are negligible when using multiple different seeds to compare.
+ Should also be ran with [`~utils.set_seed`] for the best results.
+ data_seed (`int`, defaults to `None`):
+ The seed to use for the underlying generator when using `use_seedable_sampler`. If `None`, the generator
+ will use the current default seed from torch.
+ non_blocking (`bool`, defaults to `False`):
+ If set to `True`, the dataloader prepared by the Accelerator will utilize non-blocking host-to-device
+ transfers, allowing for better overlap between dataloader communication and computation. Recommended that
+ the prepared dataloader has `pin_memory` set to `True` to work properly.
+ use_stateful_dataloader (`bool`, defaults to `False`):
+ If set to `True`, the dataloader prepared by the Accelerator will be backed by
+ [torchdata.StatefulDataLoader](https://github.com/pytorch/data/tree/main/torchdata/stateful_dataloader).
+ This requires `torchdata` version 0.8.0 or higher that supports StatefulDataLoader to be installed.
+ """
+
+ split_batches: bool = field(
+ default=False,
+ metadata={
+ "help": "Whether or not the accelerator should split the batches yielded by the dataloaders across the devices. If"
+ " `True` the actual batch size used will be the same on any kind of distributed processes, but it must be a"
+ " round multiple of the `num_processes` you are using. If `False`, actual batch size used will be the one set"
+ " in your script multiplied by the number of processes."
+ },
+ )
+ dispatch_batches: bool = field(
+ default=None,
+ metadata={
+ "help": "If set to `True`, the dataloader prepared by the Accelerator is only iterated through on the main process"
+ " and then the batches are split and broadcast to each process. Will default to `True` for `DataLoader` whose"
+ " underlying dataset is an `IterableDataset`, `False` otherwise."
+ },
+ )
+ even_batches: bool = field(
+ default=True,
+ metadata={
+ "help": "If set to `True`, in cases where the total batch size across all processes does not exactly divide the"
+ " dataset, samples at the start of the dataset will be duplicated so the batch can be divided equally among"
+ " all workers."
+ },
+ )
+ use_seedable_sampler: bool = field(
+ default=False,
+ metadata={
+ "help": "Whether or not use a fully seedable random sampler ([`data_loader.SeedableRandomSampler`])."
+ "Ensures training results are fully reproducible using a different sampling technique. "
+ "While seed-to-seed results may differ, on average the differences are negligible when using"
+ "multiple different seeds to compare. Should also be ran with [`~utils.set_seed`] for the best results."
+ },
+ )
+ data_seed: int = field(
+ default=None,
+ metadata={
+ "help": "The seed to use for the underlying generator when using `use_seedable_sampler`. If `None`, the generator"
+ " will use the current default seed from torch."
+ },
+ )
+ non_blocking: bool = field(
+ default=False,
+ metadata={
+ "help": "If set to `True`, the dataloader prepared by the Accelerator will utilize non-blocking host-to-device"
+ " transfers, allowing for better overlap between dataloader communication and computation. Recommended that the"
+ " prepared dataloader has `pin_memory` set to `True` to work properly."
+ },
+ )
+ use_stateful_dataloader: bool = field(
+ default=False,
+ metadata={
+ "help": "If set to `True`, the dataloader prepared by the Accelerator will be backed by "
+ "[torchdata.StatefulDataLoader](https://github.com/pytorch/data/tree/main/torchdata/stateful_dataloader). This requires `torchdata` version 0.8.0 or higher that supports StatefulDataLoader to be installed."
+ },
+ )
+
+
+@dataclass
+class ProjectConfiguration:
+ """
+ Configuration for the Accelerator object based on inner-project needs.
+
+ Args:
+ project_dir (`str`, defaults to `None`):
+ A path to a directory for storing data.
+ logging_dir (`str`, defaults to `None`):
+ A path to a directory for storing logs of locally-compatible loggers. If None, defaults to `project_dir`.
+ automatic_checkpoint_naming (`bool`, defaults to `False`):
+ Whether saved states should be automatically iteratively named.
+ total_limit (`int`, defaults to `None`):
+ The maximum number of total saved states to keep.
+ iteration (`int`, defaults to `0`):
+ The current save iteration.
+ save_on_each_node (`bool`, defaults to `False`):
+ When doing multi-node distributed training, whether to save models and checkpoints on each node, or only on
+ the main one.
+ """
+
+ project_dir: str = field(default=None, metadata={"help": "A path to a directory for storing data."})
+ logging_dir: str = field(
+ default=None,
+ metadata={
+ "help": "A path to a directory for storing logs of locally-compatible loggers. If None, defaults to `project_dir`."
+ },
+ )
+ automatic_checkpoint_naming: bool = field(
+ default=False,
+ metadata={"help": "Whether saved states should be automatically iteratively named."},
+ )
+
+ total_limit: int = field(
+ default=None,
+ metadata={"help": "The maximum number of total saved states to keep."},
+ )
+
+ iteration: int = field(
+ default=0,
+ metadata={"help": "The current save iteration."},
+ )
+
+ save_on_each_node: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "When doing multi-node distributed training, whether to save models and checkpoints on each node, or"
+ " only on the main one"
+ )
+ },
+ )
+
+ def set_directories(self, project_dir: Optional[str] = None):
+ "Sets `self.project_dir` and `self.logging_dir` to the appropriate values."
+ self.project_dir = project_dir
+ if self.logging_dir is None:
+ self.logging_dir = project_dir
+
+ def __post_init__(self):
+ self.set_directories(self.project_dir)
+
+
+@dataclass
+class GradientAccumulationPlugin(KwargsHandler):
+ """
+ A plugin to configure gradient accumulation behavior. You can only pass one of `gradient_accumulation_plugin` or
+ `gradient_accumulation_steps` to [`Accelerator`]. Passing both raises an error.
+
+ Parameters:
+ num_steps (`int`):
+ The number of steps to accumulate gradients for.
+ adjust_scheduler (`bool`, *optional*, defaults to `True`):
+ Whether to adjust the scheduler steps to account for the number of steps being accumulated. Should be
+ `True` if the used scheduler was not adjusted for gradient accumulation.
+ sync_with_dataloader (`bool`, *optional*, defaults to `True`):
+ Whether to synchronize setting the gradients when at the end of the dataloader.
+ sync_each_batch (`bool`, *optional*):
+ Whether to synchronize setting the gradients at each data batch. Setting to `True` may reduce memory
+ requirements when using gradient accumulation with distributed training, at expense of speed.
+
+ Example:
+
+ ```python
+ from accelerate.utils import GradientAccumulationPlugin
+
+ gradient_accumulation_plugin = GradientAccumulationPlugin(num_steps=2)
+ accelerator = Accelerator(gradient_accumulation_plugin=gradient_accumulation_plugin)
+ ```
+ """
+
+ num_steps: int = field(
+ default=None,
+ metadata={"help": "The number of steps to accumulate gradients for."},
+ )
+ adjust_scheduler: bool = field(
+ default=True,
+ metadata={
+ "help": "Whether to adjust the scheduler steps to account for the number of steps being accumulated. Should be `True` if the used scheduler was not adjusted for gradient accumulation."
+ },
+ )
+ sync_with_dataloader: bool = field(
+ default=True,
+ metadata={
+ "help": "Whether to synchronize setting the gradients when at the end of the dataloader. Should only be set to `False` if you know what you're doing."
+ },
+ )
+ sync_each_batch: bool = field(
+ default=False,
+ metadata={
+ "help": "Whether to synchronize setting the gradients at each data batch. Setting to `True` may reduce memory requirements when using gradient accumulation with distributed training, at expense of speed."
+ },
+ )
+
+
+@dataclass
+class TorchDynamoPlugin(KwargsHandler):
+ """
+ This plugin is used to compile a model with PyTorch 2.0
+
+ Args:
+ backend (`DynamoBackend`, defaults to `None`):
+ A valid Dynamo backend. See https://pytorch.org/docs/stable/torch.compiler.html for more details.
+ mode (`str`, defaults to `None`):
+ Possible options are 'default', 'reduce-overhead' or 'max-autotune'.
+ fullgraph (`bool`, defaults to `None`):
+ Whether it is ok to break model into several subgraphs.
+ dynamic (`bool`, defaults to `None`):
+ Whether to use dynamic shape for tracing.
+ options (`Any`, defaults to `None`):
+ A dictionary of options to pass to the backend.
+ disable (`bool`, defaults to `False`):
+ Turn torch.compile() into a no-op for testing
+ use_regional_compilation (`bool`, defaults to `None`):
+ Use it to reduce the cold start compilation time of torch.compile() by targeting repeated blocks of the
+ same class and compiling them sequentially to hit the compiler's cache. For example, in `GPT2LMHeadModel`,
+ the repeated block/class is `GPT2Block`, and can be accessed as `model.transformer.h[0]`. The rest of the
+ model (e.g model.lm_head) is compiled separately.
+ """
+
+ backend: DynamoBackend = field(
+ default=None,
+ metadata={"help": f"Possible options are {[b.value.lower() for b in DynamoBackend]}"},
+ )
+ mode: str = field(
+ default=None,
+ metadata={"help": "Possible options are 'default', 'reduce-overhead' or 'max-autotune'"},
+ )
+ fullgraph: bool = field(
+ default=None,
+ metadata={"help": "Whether it is ok to break model into several subgraphs"},
+ )
+ dynamic: bool = field(default=None, metadata={"help": "Whether to use dynamic shape for tracing"})
+ options: Any = field(
+ default=None,
+ metadata={"help": "A dictionary of options to pass to the backend."},
+ )
+ disable: bool = field(
+ default=False,
+ metadata={"help": "Turn torch.compile() into a no-op for testing"},
+ )
+
+ use_regional_compilation: bool = field(
+ default=None,
+ metadata={
+ "help": (
+ # https://pytorch.org/tutorials/recipes/regional_compilation.html
+ "Use it to reduce the cold start compilation time of torch.compile() by targeting repeated "
+ "blocks of the same class and compiling them sequentially to hit the compiler's cache. For "
+ "example, in `GPT2LMHeadModel`, the repeated block/class is `GPT2Block`, and can be accessed "
+ "as `model.transformer.h[0]`. The rest of the model (e.g model.lm_head) is compiled separately."
+ )
+ },
+ )
+
+ def __post_init__(self):
+ prefix = "ACCELERATE_DYNAMO_"
+ if self.backend is None:
+ self.backend = os.environ.get(prefix + "BACKEND", "no")
+ self.backend = DynamoBackend(self.backend.upper())
+
+ if self.mode is None:
+ self.mode = os.environ.get(prefix + "MODE", "default")
+ if self.fullgraph is None:
+ self.fullgraph = str_to_bool(os.environ.get(prefix + "USE_FULLGRAPH", "False")) == 1
+ if self.use_regional_compilation is None:
+ self.use_regional_compilation = (
+ str_to_bool(os.environ.get(prefix + "USE_REGIONAL_COMPILATION", "False")) == 1
+ )
+
+ if self.dynamic is None and os.environ.get(prefix + "USE_DYNAMIC", None) is not None:
+ self.dynamic = str_to_bool(os.environ.get(prefix + "USE_DYNAMIC", "False")) == 1
+
+ def to_dict(self):
+ dynamo_config = copy.deepcopy(self.__dict__)
+ dynamo_config["backend"] = dynamo_config["backend"].value.lower()
+ return dynamo_config
+
+ def to_kwargs(self):
+ kwargs = super().to_kwargs()
+ kwargs.pop("use_regional_compilation", None)
+ return kwargs
+
+
+@dataclass
+class DeepSpeedPlugin:
+ """
+ This plugin is used to integrate DeepSpeed.
+
+ Args:
+ hf_ds_config (`Any`, defaults to `None`):
+ Path to DeepSpeed config file or dict or an object of class `accelerate.utils.deepspeed.HfDeepSpeedConfig`.
+ gradient_accumulation_steps (`int`, defaults to `None`):
+ Number of steps to accumulate gradients before updating optimizer states. If not set, will use the value
+ from the `Accelerator` directly.
+ gradient_clipping (`float`, defaults to `None`):
+ Enable gradient clipping with value.
+ zero_stage (`int`, defaults to `None`):
+ Possible options are 0, 1, 2, 3. Default will be taken from environment variable.
+ is_train_batch_min (`bool`, defaults to `True`):
+ If both train & eval dataloaders are specified, this will decide the `train_batch_size`.
+ offload_optimizer_device (`str`, defaults to `None`):
+ Possible options are none|cpu|nvme. Only applicable with ZeRO Stages 2 and 3.
+ offload_param_device (`str`, defaults to `None`):
+ Possible options are none|cpu|nvme. Only applicable with ZeRO Stage 3.
+ offload_optimizer_nvme_path (`str`, defaults to `None`):
+ Possible options are /nvme|/local_nvme. Only applicable with ZeRO Stage 3.
+ offload_param_nvme_path (`str`, defaults to `None`):
+ Possible options are /nvme|/local_nvme. Only applicable with ZeRO Stage 3.
+ zero3_init_flag (`bool`, defaults to `None`):
+ Flag to indicate whether to save 16-bit model. Only applicable with ZeRO Stage-3.
+ zero3_save_16bit_model (`bool`, defaults to `None`):
+ Flag to indicate whether to save 16-bit model. Only applicable with ZeRO Stage-3.
+ transformer_moe_cls_names (`str`, defaults to `None`):
+ Comma-separated list of Transformers MoE layer class names (case-sensitive). For example,
+ `MixtralSparseMoeBlock`, `Qwen2MoeSparseMoeBlock`, `JetMoEAttention`, `JetMoEBlock`, etc.
+ enable_msamp (`bool`, defaults to `None`):
+ Flag to indicate whether to enable MS-AMP backend for FP8 training.
+ msasmp_opt_level (`Optional[Literal["O1", "O2"]]`, defaults to `None`):
+ Optimization level for MS-AMP (defaults to 'O1'). Only applicable if `enable_msamp` is True. Should be one
+ of ['O1' or 'O2'].
+ """
+
+ hf_ds_config: Any = field(
+ default=None,
+ metadata={
+ "help": "path to DeepSpeed config file or dict or an object of class `accelerate.utils.deepspeed.HfDeepSpeedConfig`."
+ },
+ )
+ gradient_accumulation_steps: int = field(
+ default=None,
+ metadata={
+ "help": "Number of steps to accumulate gradients before updating optimizer states. If not set, will use the value from the `Accelerator` directly."
+ },
+ )
+ gradient_clipping: float = field(default=None, metadata={"help": "Enable gradient clipping with value"})
+ zero_stage: int = field(
+ default=None,
+ metadata={"help": "Possible options are 0,1,2,3; Default will be taken from environment variable"},
+ )
+ is_train_batch_min: bool = field(
+ default=True,
+ metadata={"help": "If both train & eval dataloaders are specified, this will decide the train_batch_size"},
+ )
+ offload_optimizer_device: str = field(
+ default=None,
+ metadata={"help": "Possible options are none|cpu|nvme. Only applicable with ZeRO Stages 2 and 3."},
+ )
+ offload_param_device: str = field(
+ default=None,
+ metadata={"help": "Possible options are none|cpu|nvme. Only applicable with ZeRO Stage 3."},
+ )
+ offload_optimizer_nvme_path: str = field(
+ default=None,
+ metadata={"help": "Possible options are /nvme|/local_nvme. Only applicable with ZeRO Stage 3."},
+ )
+ offload_param_nvme_path: str = field(
+ default=None,
+ metadata={"help": "Possible options are /nvme|/local_nvme. Only applicable with ZeRO Stage 3."},
+ )
+ zero3_init_flag: bool = field(
+ default=None,
+ metadata={
+ "help": "Flag to indicate whether to enable `deepspeed.zero.Init` for constructing massive models."
+ "Only applicable with ZeRO Stage-3."
+ },
+ )
+ zero3_save_16bit_model: bool = field(
+ default=None,
+ metadata={"help": "Flag to indicate whether to save 16-bit model. Only applicable with ZeRO Stage-3."},
+ )
+ transformer_moe_cls_names: str = field(
+ default=None,
+ metadata={
+ "help": "comma-separated list of transformers MoE layer class names (case-sensitive), e.g : "
+ " `MixtralSparseMoeBlock`, `Qwen2MoeSparseMoeBlock`, `JetMoEAttention,JetMoEBlock` ..."
+ },
+ )
+ enable_msamp: bool = field(
+ default=None,
+ metadata={"help": "Flag to indicate whether to enable MS-AMP backend for FP8 training."},
+ )
+ msamp_opt_level: Optional[Literal["O1", "O2"]] = field(
+ default=None,
+ metadata={
+ "help": "Optimization level for MS-AMP (defaults to 'O1'). Only applicable if `enable_msamp` is True. Should be one of ['O1' or 'O2']."
+ },
+ )
+
+ def __post_init__(self):
+ from .deepspeed import HfDeepSpeedConfig
+
+ if self.gradient_accumulation_steps is None:
+ gas = os.environ.get("ACCELERATE_GRADIENT_ACCUMULATION_STEPS", "auto")
+ self.gradient_accumulation_steps = int(gas) if gas.isdigit() else gas
+
+ if self.gradient_clipping is None:
+ gradient_clipping = os.environ.get("ACCELERATE_GRADIENT_CLIPPING", "auto")
+ self.gradient_clipping = gradient_clipping if gradient_clipping == "auto" else float(gradient_clipping)
+
+ if self.zero_stage is None:
+ self.zero_stage = int(os.environ.get("ACCELERATE_DEEPSPEED_ZERO_STAGE", 2))
+
+ if self.offload_optimizer_device is None:
+ self.offload_optimizer_device = os.environ.get("ACCELERATE_DEEPSPEED_OFFLOAD_OPTIMIZER_DEVICE", "none")
+
+ if self.offload_param_device is None:
+ self.offload_param_device = os.environ.get("ACCELERATE_DEEPSPEED_OFFLOAD_PARAM_DEVICE", "none")
+
+ if self.offload_optimizer_nvme_path is None:
+ self.offload_optimizer_nvme_path = os.environ.get(
+ "ACCELERATE_DEEPSPEED_OFFLOAD_OPTIMIZER_NVME_PATH", "none"
+ )
+
+ if self.offload_param_nvme_path is None:
+ self.offload_param_nvme_path = os.environ.get("ACCELERATE_DEEPSPEED_OFFLOAD_PARAM_NVME_PATH", "none")
+
+ if self.zero3_save_16bit_model is None:
+ self.zero3_save_16bit_model = (
+ os.environ.get("ACCELERATE_DEEPSPEED_ZERO3_SAVE_16BIT_MODEL", "false").lower() == "true"
+ )
+ if self.enable_msamp is None:
+ self.enable_msamp = os.environ.get("ACCELERATE_FP8_BACKEND", None) == "MSAMP"
+
+ if self.msamp_opt_level is None:
+ self.msamp_opt_level = os.environ.get("ACCELERATE_FP8_OPT_LEVEL", "O1")
+
+ if self.hf_ds_config is None:
+ self.hf_ds_config = os.environ.get("ACCELERATE_DEEPSPEED_CONFIG_FILE", "none")
+
+ if (
+ isinstance(self.hf_ds_config, dict)
+ or (isinstance(self.hf_ds_config, str) and self.hf_ds_config != "none")
+ or isinstance(self.hf_ds_config, HfDeepSpeedConfig)
+ ):
+ if not isinstance(self.hf_ds_config, HfDeepSpeedConfig):
+ self.hf_ds_config = HfDeepSpeedConfig(self.hf_ds_config)
+ if "gradient_accumulation_steps" not in self.hf_ds_config.config:
+ self.hf_ds_config.config["gradient_accumulation_steps"] = 1
+ if "zero_optimization" not in self.hf_ds_config.config:
+ raise ValueError("Please specify the ZeRO optimization config in the DeepSpeed config.")
+
+ self._deepspeed_config_checks()
+ plugin_to_config_mapping = {
+ "gradient_accumulation_steps": "gradient_accumulation_steps",
+ "gradient_clipping": "gradient_clipping",
+ "zero_stage": "zero_optimization.stage",
+ "offload_optimizer_device": "zero_optimization.offload_optimizer.device",
+ "offload_param_device": "zero_optimization.offload_param.device",
+ "offload_param_nvme_path": "zero_optimization.offload_param.nvme_path",
+ "offload_optimizer_nvme_path": "zero_optimization.offload_optimizer.nvme_path",
+ "zero3_save_16bit_model": "zero_optimization.stage3_gather_16bit_weights_on_model_save",
+ }
+ kwargs = {v: getattr(self, k) for k, v in plugin_to_config_mapping.items() if getattr(self, k) is not None}
+ for key in kwargs.keys():
+ self.fill_match(key, **kwargs, must_match=False)
+ self.hf_ds_config.set_stage_and_offload()
+
+ # filling the missing values in the class attributes from the DeepSpeed config
+ # when using the DeepSpeed config file.
+ for key, value in plugin_to_config_mapping.items():
+ config_value = self.hf_ds_config.get_value(value)
+ if config_value is not None and config_value != "auto":
+ setattr(self, key, config_value)
+ else:
+ config = {
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ "gradient_accumulation_steps": self.gradient_accumulation_steps,
+ "zero_optimization": {
+ "stage": self.zero_stage,
+ "offload_optimizer": {
+ "device": self.offload_optimizer_device,
+ "nvme_path": (
+ self.offload_optimizer_nvme_path if self.offload_optimizer_device == "nvme" else None
+ ),
+ },
+ "offload_param": {
+ "device": self.offload_param_device,
+ "nvme_path": (self.offload_param_nvme_path if self.offload_param_device == "nvme" else None),
+ },
+ "stage3_gather_16bit_weights_on_model_save": self.zero3_save_16bit_model,
+ },
+ }
+ if self.gradient_clipping:
+ config["gradient_clipping"] = self.gradient_clipping
+ self.hf_ds_config = HfDeepSpeedConfig(config)
+
+ self.deepspeed_config = self.hf_ds_config.config
+ self.deepspeed_config["steps_per_print"] = float("inf") # this will stop deepspeed from logging @ stdout
+ if self.zero3_init_flag is None:
+ self.zero3_init_flag = (
+ str_to_bool(
+ os.environ.get(
+ "ACCELERATE_DEEPSPEED_ZERO3_INIT",
+ str(self.hf_ds_config.is_zero3()),
+ )
+ )
+ == 1
+ )
+ if self.zero3_init_flag and not self.hf_ds_config.is_zero3():
+ warnings.warn("DeepSpeed Zero3 Init flag is only applicable for ZeRO Stage 3. Setting it to False.")
+ self.zero3_init_flag = False
+ # NOTE: Set to False by default, will be set to `True` automatically if it's the first plugin passed
+ # to the `Accelerator`'s `deepspeed_plugin` param, *or* `AcceleratorState().enable_deepspeed_plugin(plugin_key)` is manually called
+ self._set_selected(False)
+
+ # Ignore if it's already set
+ if self.enable_msamp and "msamp" not in self.deepspeed_config:
+ if self.zero_stage == 3:
+ raise NotImplementedError(
+ "MS-AMP is not supported for ZeRO Stage 3. Please use ZeRO Stage 0, 1, or 2 instead."
+ )
+ if self.msamp_opt_level not in ["O1", "O2"]:
+ raise ValueError("Invalid optimization level for MS-AMP. Please use one of ['O1' or'O2'].")
+ self.deepspeed_config["msamp"] = {
+ "enabled": True,
+ "opt_level": self.msamp_opt_level,
+ }
+
+ def fill_match(self, ds_key_long, mismatches=None, must_match=True, **kwargs):
+ mismatches = [] if mismatches is None else mismatches
+ config, ds_key = self.hf_ds_config.find_config_node(ds_key_long)
+ if config is None:
+ return
+
+ if config.get(ds_key) == "auto":
+ if ds_key_long in kwargs:
+ config[ds_key] = kwargs[ds_key_long]
+ return
+ else:
+ raise ValueError(
+ f"`{ds_key_long}` not found in kwargs. "
+ f"Please specify `{ds_key_long}` without `auto` (set to correct value) in the DeepSpeed config file or "
+ "pass it in kwargs."
+ )
+
+ if not must_match:
+ return
+
+ ds_val = config.get(ds_key)
+ if ds_val is not None and ds_key_long in kwargs:
+ if ds_val != kwargs[ds_key_long]:
+ mismatches.append(f"- ds {ds_key_long}={ds_val} vs arg {ds_key_long}={kwargs[ds_key_long]}")
+
+ def is_auto(self, ds_key_long):
+ val = self.hf_ds_config.get_value(ds_key_long)
+ if val is None:
+ return False
+ else:
+ return val == "auto"
+
+ def get_value(self, ds_key_long, default=None):
+ return self.hf_ds_config.get_value(ds_key_long, default)
+
+ def deepspeed_config_process(self, prefix="", mismatches=None, config=None, must_match=True, **kwargs):
+ """Process the DeepSpeed config with the values from the kwargs."""
+ mismatches = [] if mismatches is None else mismatches
+ if config is None:
+ config = self.deepspeed_config
+ for key, value in config.items():
+ if isinstance(value, dict):
+ self.deepspeed_config_process(
+ prefix=prefix + key + ".",
+ mismatches=mismatches,
+ config=value,
+ must_match=must_match,
+ **kwargs,
+ )
+ else:
+ self.fill_match(prefix + key, mismatches, must_match=must_match, **kwargs)
+ if len(mismatches) > 0 and prefix == "":
+ mismatches_msg = "\n".join(mismatches)
+ raise ValueError(
+ "Please correct the following DeepSpeed config values that mismatch kwargs "
+ f" values:\n{mismatches_msg}\nThe easiest method is to set these DeepSpeed config values to 'auto'."
+ )
+
+ def set_mixed_precision(self, mixed_precision):
+ ds_config = self.deepspeed_config
+ kwargs = {
+ "fp16.enabled": mixed_precision == "fp16",
+ # When training in fp8, we still rely on bf16 autocast for the core mixed precision
+ "bf16.enabled": mixed_precision in ("bf16", "fp8"),
+ }
+ if mixed_precision == "fp16":
+ if "fp16" not in ds_config:
+ ds_config["fp16"] = {"enabled": True, "auto_cast": True}
+ elif mixed_precision in ("bf16", "fp8"):
+ if "bf16" not in ds_config:
+ ds_config["bf16"] = {"enabled": True}
+
+ if mixed_precision == "fp8" and self.enable_msamp:
+ if "msamp" not in ds_config:
+ ds_config["msamp"] = {
+ "enabled": True,
+ "opt_level": self.msamp_opt_level,
+ }
+
+ if mixed_precision != "no":
+ diff_dtype = "bf16" if mixed_precision == "fp16" else "fp16"
+ if str(ds_config.get(diff_dtype, {}).get("enabled", "False")).lower() == "true":
+ raise ValueError(
+ f"`--mixed_precision` arg cannot be set to `{mixed_precision}` when `{diff_dtype}` is set in the DeepSpeed config file."
+ )
+ for dtype in ["fp16", "bf16"]:
+ if dtype not in ds_config:
+ ds_config[dtype] = {"enabled": False}
+ self.fill_match("fp16.enabled", must_match=False, **kwargs)
+ self.fill_match("bf16.enabled", must_match=False, **kwargs)
+
+ def set_deepspeed_weakref(self):
+ from .imports import is_transformers_available
+
+ ds_config = copy.deepcopy(self.deepspeed_config)
+ if self.zero3_init_flag:
+ if not is_transformers_available():
+ raise Exception(
+ "When `zero3_init_flag` is set, it requires Transformers to be installed. "
+ "Please run `pip install transformers`."
+ )
+ if "gradient_accumulation_steps" not in ds_config or ds_config["gradient_accumulation_steps"] == "auto":
+ ds_config["gradient_accumulation_steps"] = 1
+ if "train_micro_batch_size_per_gpu" not in ds_config or ds_config["train_micro_batch_size_per_gpu"] == "auto":
+ ds_config["train_micro_batch_size_per_gpu"] = 1
+ if ds_config.get("train_batch_size", None) == "auto":
+ del ds_config["train_batch_size"]
+
+ if compare_versions("transformers", "<", "4.46"):
+ from transformers.deepspeed import (
+ HfDeepSpeedConfig,
+ unset_hf_deepspeed_config,
+ )
+ else:
+ from transformers.integrations import (
+ HfDeepSpeedConfig,
+ unset_hf_deepspeed_config,
+ )
+
+ unset_hf_deepspeed_config()
+ self.dschf = HfDeepSpeedConfig(ds_config) # keep this object alive # noqa
+
+ def is_zero3_init_enabled(self):
+ return self.zero3_init_flag
+
+ @contextmanager
+ def zero3_init_context_manager(self, enable=False):
+ old = self.zero3_init_flag
+ if old == enable:
+ yield
+ else:
+ self.zero3_init_flag = enable
+ self.dschf = None
+ self.set_deepspeed_weakref()
+ yield
+ self.zero3_init_flag = old
+ self.dschf = None
+ self.set_deepspeed_weakref()
+
+ def _deepspeed_config_checks(self):
+ env_variable_names_to_ignore = [
+ "ACCELERATE_GRADIENT_ACCUMULATION_STEPS",
+ "ACCELERATE_GRADIENT_CLIPPING",
+ "ACCELERATE_DEEPSPEED_ZERO_STAGE",
+ "ACCELERATE_DEEPSPEED_OFFLOAD_OPTIMIZER_DEVICE",
+ "ACCELERATE_DEEPSPEED_OFFLOAD_PARAM_DEVICE",
+ "ACCELERATE_DEEPSPEED_OFFLOAD_PARAM_NVME_PATH",
+ "ACCELERATE_DEEPSPEED_OFFLOAD_OPTIMIZER_NVME_PATH",
+ "ACCELERATE_DEEPSPEED_ZERO3_SAVE_16BIT_MODEL",
+ "ACCELERATE_MIXED_PRECISION",
+ ]
+ env_variable_names_to_ignore = [
+ name.replace("ACCELERATE_", "").replace("DEEPSPEED_", "").lower() for name in env_variable_names_to_ignore
+ ]
+
+ deepspeed_fields_from_accelerate_config = os.environ.get("ACCELERATE_CONFIG_DS_FIELDS", "").split(",")
+
+ if any(name in env_variable_names_to_ignore for name in deepspeed_fields_from_accelerate_config):
+ raise ValueError(
+ f"When using `deepspeed_config_file`, the following accelerate config variables will be ignored: {env_variable_names_to_ignore}.\n"
+ "Please specify them appropriately in the DeepSpeed config file.\n"
+ "If you are using an accelerate config file, remove others config variables mentioned in the above specified list.\n"
+ "The easiest method is to create a new config following the questionnaire via `accelerate config`.\n"
+ "It will only ask for the necessary config variables when using `deepspeed_config_file`."
+ )
+
+ def set_moe_leaf_modules(self, model):
+ if self.transformer_moe_cls_names is None:
+ self.transformer_moe_cls_names = os.environ.get("ACCELERATE_DEEPSPEED_MOE_LAYER_CLS_NAMES", None)
+ if self.transformer_moe_cls_names is not None:
+ if compare_versions("deepspeed", "<", "0.14.0"):
+ raise ImportError("DeepSpeed version must be >= 0.14.0 to use MOE support. Please update DeepSpeed.")
+ from deepspeed.utils import set_z3_leaf_modules
+
+ class_names = self.transformer_moe_cls_names.split(",")
+ transformer_moe_cls = []
+ for layer_class in class_names:
+ transformer_cls = get_module_class_from_name(model, layer_class)
+ if transformer_cls is None:
+ raise Exception(
+ f"Could not find a transformer layer class called '{layer_class}' to wrap in the model."
+ )
+ else:
+ transformer_moe_cls.append(transformer_cls)
+ set_z3_leaf_modules(model, transformer_moe_cls) # z3_leaf
+
+ def select(self, _from_accelerator_state: bool = False):
+ """
+ Sets the HfDeepSpeedWeakref to use the current deepspeed plugin configuration
+ """
+ if not _from_accelerator_state:
+ raise ValueError(
+ "A `DeepSpeedPlugin` object must be enabled manually by calling `AcceleratorState().enable_deepspeed_plugin(plugin_key)`."
+ )
+ self.set_deepspeed_weakref()
+ self._set_selected(True)
+
+ def _unselect(self):
+ self._set_selected(False)
+
+ def _set_selected(self, value: bool):
+ """
+ Private setter for the 'enabled' attribute.
+ """
+ self._selected = value
+
+ @property
+ def selected(self):
+ return self._selected
+
+ @selected.setter
+ def selected(self, value):
+ raise NotImplementedError(
+ "'enabled' can only be set through calling 'AcceleratorState().enable_deepspeed_plugin(key)'."
+ )
+
+
+@dataclass
+class FullyShardedDataParallelPlugin:
+ """
+ This plugin is used to enable fully sharded data parallelism.
+
+ Args:
+ fsdp_version (`int`, defaults to `1`):
+ The version of FSDP to use. Defaults to 1. If set to 2, launcher expects the config to be converted to
+ FSDP2 format.
+ sharding_strategy (`Union[str, torch.distributed.fsdp.ShardingStrategy]`, defaults to `'FULL_SHARD'`):
+ Sharding strategy to use. Should be either a `str` or an instance of
+ `torch.distributed.fsdp.fully_sharded_data_parallel.ShardingStrategy`. Is deprecated in favor of
+ `reshard_after_forward`.
+ reshard_after_forward (`Union[str, torch.distributed.fsdp.ShardingStrategy, bool]`, defaults to `'FULL_SHARD'` for `fsdp_version=1` and `True` for `fsdp_version=2`):
+ Sharding strategy to use. Should be a bool if `fsdp_version` is set to 2 else a `str` or an instance of
+ `torch.distributed.fsdp.fully_sharded_data_parallel.ShardingStrategy`.
+ backward_prefetch (`Union[str, torch.distributed.fsdp.BackwardPrefetch]`, defaults to `'NO_PREFETCH'`):
+ Backward prefetch strategy to use. Should be either a `str` or an instance of
+ `torch.distributed.fsdp.fully_sharded_data_parallel.BackwardPrefetch`.
+ mixed_precision_policy (`Optional[Union[dict, str, torch.distributed.fsdp.MixedPrecision, torch.distributed.fsdp.MixedPrecisionPolicy]]`, defaults to `None`):
+ A config to enable mixed precision training with FullyShardedDataParallel. If passing in a `dict`, it
+ should have the following keys: `param_dtype`, `reduce_dtype`, and `buffer_dtype`, can be an instance of
+ `torch.distributed.fsdp.MixedPrecisionPolicy` if `fsdp_version` is set to 2. If passing in a `str`, it
+ should be one of the following values: fp8, fp16, bf16, fp32, and used to set `param_dtype`,
+ `reduce_dtype`, and `buffer_dtype`.
+ auto_wrap_policy (`Optional(Union[Callable, Literal["transformer_based_wrap", "size_based_wrap", "no_wrap"]]), defaults to `NO_WRAP`):
+ A callable or string specifying a policy to recursively wrap layers with FSDP. If a string, it must be one
+ of `transformer_based_wrap`, `size_based_wrap`, or `no_wrap`. See
+ `torch.distributed.fsdp.wrap.size_based_wrap_policy` for a direction on what it should look like.
+ cpu_offload (`Union[bool, torch.distributed.fsdp.CPUOffload, torch.distributed.fsdp.CPUOffloadPolicy]`, defaults to `False`):
+ Whether to offload parameters to CPU. Should be either a `bool` or an instance of
+ `torch.distributed.fsdp.fully_sharded_data_parallel.CPUOffload` or
+ `torch.distributed.fsdp.fully_sharded_data_parallel.CPUOffloadPolicy` if `fsdp_version` is set to 2.
+ ignored_modules (`Optional[Union[Iterable[torch.nn.Module], str]]`, defaults to `None`):
+ A list of modules to ignore when wrapping with FSDP. When passing a string, will match the modules by name
+ using regex fullmatch. If `fsdp_version` is set to 2, the modules are converted to parameters and used.
+ state_dict_type (`Union[str, torch.distributed.fsdp.StateDictType]`, defaults to `'FULL_STATE_DICT'`):
+ State dict type to use. If a string, it must be one of `full_state_dict`, `local_state_dict`, or
+ `sharded_state_dict`.
+ state_dict_config (`Optional[Union[torch.distributed.fsdp.FullStateDictConfig, torch.distributed.fsdp.ShardedStateDictConfig]`, defaults to `None`):
+ State dict config to use. Is determined based on the `state_dict_type` if not passed in.
+ optim_state_dict_config (`Optional[Union[torch.distributed.fsdp.FullOptimStateDictConfig, torch.distributed.fsdp.ShardedOptimStateDictConfig]`, defaults to `None`):
+ Optim state dict config to use. Is determined based on the `state_dict_type` if not passed in.
+ limit_all_gathers (`bool`, defaults to `True`):
+ Whether to have FSDP explicitly synchronizes the CPU thread to prevent too many in-flight all-gathers. This
+ bool only affects the sharded strategies that schedule all-gathers. Enabling this can help lower the number
+ of CUDA malloc retries.
+ use_orig_params (`bool`, defaults to `False`):
+ Whether to use the original parameters for the optimizer.
+ param_init_fn (`Optional[Callable[[torch.nn.Module], None]`, defaults to `None`):
+ A `Callable[torch.nn.Module] -> None` that specifies how modules that are currently on the meta device
+ should be initialized onto an actual device. Only applicable when `sync_module_states` is `True`. By
+ default is a `lambda` which calls `to_empty` on the module.
+ sync_module_states (`bool`, defaults to `False`):
+ Whether each individually wrapped FSDP unit should broadcast module parameters from rank 0 to ensure they
+ are the same across all ranks after initialization. Defaults to `False` unless `cpu_ram_efficient_loading`
+ is `True`, then will be forcibly enabled.
+ forward_prefetch (`bool`, defaults to `False`):
+ Whether to have FSDP explicitly prefetches the next upcoming all-gather while executing in the forward
+ pass. only use with Static graphs.
+ activation_checkpointing (`bool`, defaults to `False`):
+ A technique to reduce memory usage by clearing activations of certain layers and recomputing them during a
+ backward pass. Effectively, this trades extra computation time for reduced memory usage.
+ cpu_ram_efficient_loading (`bool`, defaults to `None`):
+ If True, only the first process loads the pretrained model checkoint while all other processes have empty
+ weights. Only applicable for Transformers. When using this, `sync_module_states` needs to be `True`.
+ transformer_cls_names_to_wrap (`Optional[List[str]]`, defaults to `None`):
+ A list of transformer layer class names to wrap. Only applicable when `auto_wrap_policy` is
+ `transformer_based_wrap`.
+ min_num_params (`Optional[int]`, defaults to `None`):
+ The minimum number of parameters a module must have to be wrapped. Only applicable when `auto_wrap_policy`
+ is `size_based_wrap`.
+ """
+
+ fsdp_version: int = field(
+ default=None,
+ metadata={
+ "help": "The version of FSDP to use. Defaults to 1. If set to 2, launcher expects the config to be converted to FSDP2 format."
+ },
+ )
+
+ sharding_strategy: Union[str, "torch.distributed.fsdp.ShardingStrategy"] = field(
+ default=None,
+ metadata={
+ "help": "Sharding strategy to use. Should be either a `str` or an instance of `torch.distributed.fsdp.fully_sharded_data_parallel.ShardingStrategy`. Defaults to 'FULL_SHARD'. Is deprecated in favor of `reshard_after_forward` "
+ },
+ )
+
+ reshard_after_forward: Union[str, "torch.distributed.fsdp.ShardingStrategy", bool] = field(
+ default=None,
+ metadata={
+ "help": "Sharding strategy to use. Should be a bool if `fsdp_version` is set to 2 else a `str` or an instance of `torch.distributed.fsdp.fully_sharded_data_parallel.ShardingStrategy`. Defaults to 'FULL_SHARD'"
+ },
+ )
+ backward_prefetch: Optional[Union[str, "torch.distributed.fsdp.BackwardPrefetch"]] = field(
+ default=None,
+ metadata={
+ "help": "Backward prefetch strategy to use. Should be either a `str` or an instance of `torch.distributed.fsdp.fully_sharded_data_parallel.BackwardPrefetch`. Defaults to 'NO_PREFETCH'. This becomes obsolete in FSDP2."
+ },
+ )
+ mixed_precision_policy: Optional[
+ Union[
+ dict,
+ str,
+ "torch.distributed.fsdp.MixedPrecision",
+ "torch.distributed.fsdp.MixedPrecisionPolicy",
+ ]
+ ] = field(
+ default=None,
+ metadata={
+ "help": "A config to enable mixed precision training with FullyShardedDataParallel. "
+ "If passing in a `dict`, it should have the following keys: `param_dtype`, `reduce_dtype`, and `buffer_dtype`."
+ "Can also be an instance of `torch.distributed.fsdp.MixedPrecisionPolicy` if `fsdp_version` is set to 2."
+ },
+ )
+ auto_wrap_policy: Optional[Union[Callable, Literal["transformer_based_wrap", "size_based_wrap", "no_wrap"]]] = (
+ field(
+ default=None,
+ metadata={
+ "help": "A callable or string specifying a policy to recursively wrap layers with FSDP. If a string, it must be one of `transformer_based_wrap`, `size_based_wrap`, or `no_wrap`. "
+ "Defaults to `NO_WRAP`. See `torch.distributed.fsdp.wrap.size_based_wrap_policy` for a direction on what it should look like"
+ },
+ )
+ )
+ cpu_offload: Union[
+ bool,
+ "torch.distributed.fsdp.CPUOffload",
+ "torch.distributed.fsdp.CPUOffloadPolicy",
+ ] = field(
+ default=None,
+ metadata={
+ "help": "Whether to offload parameters to CPU. Should be either a `bool` or an instance of `torch.distributed.fsdp.fully_sharded_data_parallel.CPUOffload` or `torch.distributed.fsdp.fully_sharded_data_parallel.CPUOffloadPolicy` if `fsdp_version` is set to 2. Defaults to `False`"
+ },
+ )
+ ignored_modules: Optional[Union[Iterable[torch.nn.Module], str]] = field(
+ default=None,
+ metadata={"help": "A list of modules to ignore when wrapping with FSDP."},
+ )
+
+ state_dict_type: Union[str, "torch.distributed.fsdp.StateDictType"] = field(
+ default=None,
+ metadata={
+ "help": "State dict type to use. If a string, it must be one of `full_state_dict`, `local_state_dict`, or `sharded_state_dict`. Defaults to `FULL_STATE_DICT`"
+ },
+ )
+ state_dict_config: Optional[
+ Union[
+ "torch.distributed.fsdp.FullStateDictConfig",
+ "torch.distributed.fsdp.ShardedStateDictConfig",
+ ]
+ ] = field(
+ default=None,
+ metadata={"help": "State dict config to use. Is determined based on the `state_dict_type` if not passed in."},
+ )
+ optim_state_dict_config: Optional[
+ Union[
+ "torch.distributed.fsdp.FullOptimStateDictConfig",
+ "torch.distributed.fsdp.ShardedOptimStateDictConfig",
+ ]
+ ] = field(
+ default=None,
+ metadata={
+ "help": "Optim state dict config to use. Is determined based on the `state_dict_type` if not passed in."
+ },
+ )
+ limit_all_gathers: bool = field(
+ default=True,
+ metadata={
+ "help": "Whether to have FSDP explicitly synchronizes the CPU thread to prevent "
+ "too many in-flight all-gathers. This bool only affects the sharded strategies that schedule all-gathers. "
+ "Enabling this can help lower the number of CUDA malloc retries."
+ },
+ )
+ use_orig_params: Optional[bool] = field(
+ default=None,
+ metadata={
+ "help": "Whether to use the original parameters for the optimizer. Defaults to `False`. This becomes obsolete in FSDP2."
+ },
+ )
+ param_init_fn: Optional[Callable[[torch.nn.Module], None]] = field(
+ default=None,
+ metadata={
+ "help": "A Callable[torch.nn.Module] -> None that specifies how modules "
+ "that are currently on the meta device should be initialized onto an actual device. "
+ "Only applicable when `sync_module_states` is `True`. By default is a `lambda` which calls `to_empty` on the module."
+ },
+ )
+ sync_module_states: Optional[bool] = field(
+ default=None,
+ metadata={
+ "help": "Whether each individually wrapped FSDP unit should broadcast module parameters from rank 0 "
+ "to ensure they are the same across all ranks after initialization. Defaults to `False` unless "
+ "`cpu_ram_efficient_loading` is `True`, then will be forcibly enabled. This becomes obsolete in FSDP2."
+ },
+ )
+ forward_prefetch: bool = field(
+ default=None,
+ metadata={
+ "help": "Whether to have FSDP explicitly prefetches the next upcoming "
+ "all-gather while executing in the forward pass. only use with Static graphs. Defaults to `False`"
+ },
+ )
+ activation_checkpointing: bool = field(
+ default=None,
+ metadata={
+ "help": "A technique to reduce memory usage by clearing activations of "
+ "certain layers and recomputing them during a backward pass. Effectively, this trades extra computation time "
+ "for reduced memory usage. Defaults to `False`"
+ },
+ )
+ cpu_ram_efficient_loading: bool = field(
+ default=None,
+ metadata={
+ "help": "If True, only the first process loads the pretrained model checkoint while all other processes have empty weights. "
+ "Only applicable for 🤗 Transformers. When using this, `sync_module_states` needs to be `True`. Defaults to `False`."
+ },
+ )
+ transformer_cls_names_to_wrap: Optional[list[str]] = field(
+ default=None,
+ metadata={
+ "help": "A list of transformer layer class names to wrap. Only applicable when `auto_wrap_policy` is `transformer_based_wrap`."
+ },
+ )
+ min_num_params: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": "The minimum number of parameters a module must have to be wrapped. Only applicable when `auto_wrap_policy` is `size_based_wrap`."
+ },
+ )
+
+ def __post_init__(self):
+ from torch.distributed.fsdp import BackwardPrefetch, ShardingStrategy
+
+ _fsdp2_warnings = set()
+
+ env_prefix = "FSDP_"
+ # Strategy: By default we should always assume that values are passed in, else we check the environment variables
+ if self.fsdp_version is None:
+ self.fsdp_version = int(os.environ.get(env_prefix + "VERSION", "1"))
+
+ if self.fsdp_version == 2:
+ if not is_torch_version(">=", FSDP2_PYTORCH_VERSION):
+ raise ImportError(f"FSDP2 requires PyTorch >= {FSDP2_PYTORCH_VERSION}")
+
+ if self.sharding_strategy is not None:
+ # We cannot properly detect all of the cases, as by default `args.fsdp_sharding_strategy` is set to `fully_shard`
+ # Therefore we issue a warning only if the user has explicitly set it inside their plugin
+ _fsdp2_warnings.add(
+ "sharding_strategy is deprecated in favor of reshard_after_forward. "
+ "This will be removed in a future version of Accelerate."
+ )
+ if self.fsdp_version == 1:
+ if self.sharding_strategy is None:
+ self.sharding_strategy = os.environ.get(env_prefix + "SHARDING_STRATEGY", "FULL_SHARD")
+ if isinstance(self.sharding_strategy, str):
+ if self.sharding_strategy.upper() in FSDP_SHARDING_STRATEGY:
+ self.sharding_strategy = FSDP_SHARDING_STRATEGY.index(self.sharding_strategy.upper()) + 1
+ if isinstance(self.sharding_strategy, int) or self.sharding_strategy.isdigit():
+ self.sharding_strategy = ShardingStrategy(int(self.sharding_strategy))
+ else:
+ self.sharding_strategy = ShardingStrategy[self.sharding_strategy.upper()]
+
+ # Fallback to `reshard_after_forward` in FSDP1 if `sharding_strategy` is not set
+ if self.reshard_after_forward is None and self.sharding_strategy is None:
+ reshard_after_forward = os.environ.get(
+ env_prefix + "RESHARD_AFTER_FORWARD",
+ "true" if self.fsdp_version == 2 else "FULL_SHARD",
+ )
+ if self.fsdp_version == 2:
+ self.reshard_after_forward = str_to_bool(reshard_after_forward.lower(), to_bool=True)
+ else:
+ self.reshard_after_forward = reshard_after_forward
+ if isinstance(self.reshard_after_forward, str):
+ if self.fsdp_version == 2:
+ self.reshard_after_forward = str_to_bool(self.reshard_after_forward.lower(), to_bool=True)
+ else:
+ # We need to remap based on custom enum values for user readability
+ if self.reshard_after_forward.upper() in FSDP_SHARDING_STRATEGY:
+ self.reshard_after_forward = FSDP_SHARDING_STRATEGY.index(self.reshard_after_forward.upper()) + 1
+ if isinstance(self.reshard_after_forward, int) or self.reshard_after_forward.isdigit():
+ self.reshard_after_forward = ShardingStrategy(int(self.reshard_after_forward))
+ else:
+ self.reshard_after_forward = ShardingStrategy[self.reshard_after_forward.upper()]
+
+ if self.fsdp_version == 2 and not isinstance(self.reshard_after_forward, bool):
+ raise ValueError(
+ f"reshard_after_forward set to {self.reshard_after_forward}. This is not supported with FSDP2, please set to a `bool`"
+ )
+ if self.fsdp_version == 1 and isinstance(self.reshard_after_forward, bool):
+ raise ValueError(
+ f"reshard_after_forward set to {self.reshard_after_forward}. This is not supported with FSDP1, please set to a `str` or an instance of `torch.distributed.fsdp.fully_sharded_data_parallel.ShardingStrategy`"
+ )
+
+ if self.cpu_offload is None:
+ self.cpu_offload = str_to_bool(os.environ.get(env_prefix + "OFFLOAD_PARAMS", "False")) == 1
+
+ self.set_cpu_offload() # abstracted away to hide imports due to version checks
+ self.validate_cpu_offload()
+
+ if self.backward_prefetch is None:
+ self.backward_prefetch = os.environ.get(env_prefix + "BACKWARD_PREFETCH", None)
+ if isinstance(self.backward_prefetch, str) and self.backward_prefetch.upper() == "NO_PREFETCH":
+ self.backward_prefetch = None
+ if self.backward_prefetch is not None and not isinstance(self.backward_prefetch, BackwardPrefetch):
+ if isinstance(self.backward_prefetch, str) and self.backward_prefetch.upper() in FSDP_BACKWARD_PREFETCH:
+ self.backward_prefetch = FSDP_BACKWARD_PREFETCH.index(self.backward_prefetch.upper()) + 1
+ if isinstance(self.backward_prefetch, int) or self.backward_prefetch.isdigit():
+ self.backward_prefetch = BackwardPrefetch(int(self.backward_prefetch))
+ else:
+ self.backward_prefetch = BackwardPrefetch[self.backward_prefetch.upper()]
+ if self.fsdp_version == 2 and self.backward_prefetch is not None:
+ _fsdp2_warnings.add("backward_prefetch is not supported in FSDP2. Setting backward prefetch to None.")
+ self.backward_prefetch = None
+
+ self.set_state_dict_type()
+
+ if self.auto_wrap_policy is None:
+ self.auto_wrap_policy = os.environ.get(env_prefix + "AUTO_WRAP_POLICY", "NO_WRAP")
+ if isinstance(self.auto_wrap_policy, str):
+ if self.auto_wrap_policy.upper() not in FSDP_AUTO_WRAP_POLICY:
+ raise ValueError(
+ f"Invalid auto wrap policy: {self.auto_wrap_policy}. Must be one of {FSDP_AUTO_WRAP_POLICY}"
+ )
+ from torch.distributed.fsdp.wrap import (
+ size_based_auto_wrap_policy,
+ transformer_auto_wrap_policy,
+ )
+
+ if self.auto_wrap_policy.upper() == "TRANSFORMER_BASED_WRAP":
+ self.auto_wrap_policy = transformer_auto_wrap_policy
+ if self.transformer_cls_names_to_wrap is None:
+ self.transformer_cls_names_to_wrap = os.environ.get(env_prefix + "TRANSFORMER_CLS_TO_WRAP", None)
+ if isinstance(self.transformer_cls_names_to_wrap, str):
+ self.transformer_cls_names_to_wrap = self.transformer_cls_names_to_wrap.split(",")
+ elif self.auto_wrap_policy.upper() == "SIZE_BASED_WRAP":
+ self.auto_wrap_policy = size_based_auto_wrap_policy
+ if self.min_num_params is None:
+ self.min_num_params = int(os.environ.get(env_prefix + "MIN_NUM_PARAMS", 0))
+ elif not isinstance(self.min_num_params, int):
+ raise ValueError(
+ f"`min_num_params` must be an integer. Got {self.min_num_params} of type {type(self.min_num_params)}"
+ )
+ elif self.auto_wrap_policy.upper() == "NO_WRAP":
+ self.auto_wrap_policy = None
+
+ if self.use_orig_params is None and self.fsdp_version == 1:
+ self.use_orig_params = str_to_bool(os.environ.get(env_prefix + "USE_ORIG_PARAMS", "False")) == 1
+ if self.fsdp_version == 2 and self.use_orig_params is not None:
+ _fsdp2_warnings.add("use_orig_params is obsolete in FSDP2, as FSDP2 always uses the original parameters.")
+ self.use_orig_params = None
+
+ if self.sync_module_states is None and self.fsdp_version == 1:
+ self.sync_module_states = str_to_bool(os.environ.get(env_prefix + "SYNC_MODULE_STATES", "False")) == 1
+ if self.fsdp_version == 2 and self.sync_module_states is not None:
+ _fsdp2_warnings.add(
+ "sync_module_states is obsolete in FSDP2, as it is not needed anymore."
+ "Setting sync_module_states to None."
+ )
+ self.sync_module_states = None
+
+ if self.forward_prefetch is None and self.fsdp_version == 1:
+ self.forward_prefetch = str_to_bool(os.environ.get(env_prefix + "FORWARD_PREFETCH", "False")) == 1
+ if self.fsdp_version == 2 and self.forward_prefetch is not None:
+ raise ValueError("forward_prefetch is not yet implemented in FSDP2, set to None or use `fsdp_version=1`")
+
+ if self.activation_checkpointing is None:
+ self.activation_checkpointing = (
+ str_to_bool(os.environ.get(env_prefix + "ACTIVATION_CHECKPOINTING", "False")) == 1
+ )
+
+ if self.ignored_modules is None:
+ self.ignored_modules = os.environ.get(env_prefix + "IGNORED_MODULES", None)
+
+ if self.cpu_ram_efficient_loading is None:
+ self.cpu_ram_efficient_loading = (
+ str_to_bool(os.environ.get(env_prefix + "CPU_RAM_EFFICIENT_LOADING", "False")) == 1
+ )
+ else:
+ # We still need to set it for transformers
+ os.environ[env_prefix + "CPU_RAM_EFFICIENT_LOADING"] = str(self.cpu_ram_efficient_loading)
+ # There's no need to specify sync_module_states in FSDP2
+ if self.fsdp_version == 1 and self.cpu_ram_efficient_loading and not self.sync_module_states:
+ warnings.warn(
+ "sync_module_states cannot be False since efficient cpu ram loading enabled. "
+ "Setting sync_module_states to True."
+ )
+ self.sync_module_states = True
+ if isinstance(self.mixed_precision_policy, str):
+ # override is True since self.mixed_precision_policy is not None
+ # has to be overwritten with the correct mixed precision object
+ self.set_mixed_precision(self.mixed_precision_policy, override=True)
+ elif isinstance(self.mixed_precision_policy, dict):
+ self.set_mixed_precision(self.mixed_precision_policy)
+ if self.mixed_precision_policy is not None:
+ self.validate_mixed_precision_policy()
+
+ if self.sync_module_states:
+ if is_npu_available():
+ device = torch.npu.current_device()
+ elif is_mlu_available():
+ device = torch.mlu.current_device()
+ elif is_musa_available():
+ device = torch.musa.current_device()
+ elif is_cuda_available():
+ device = torch.cuda.current_device()
+ elif is_xpu_available():
+ device = torch.xpu.current_device()
+ elif is_hpu_available():
+ device = torch.hpu.current_device()
+ else:
+ raise RuntimeError(
+ "There are currently no available devices found, must be one of 'XPU', 'CUDA', 'MLU', 'NPU', 'MUSA', or 'HPU'."
+ )
+ # Create a function that will be used to initialize the parameters of the model
+ # when using `sync_module_states`
+ self.param_init_fn = lambda x: x.to_empty(device=device, recurse=False)
+ if is_torch_version("<", "2.7.0") and self.fsdp_version == 2 and self.ignored_modules is not None:
+ _fsdp2_warnings.add(
+ "FSDP2 ignored_params/ignored_modules is not available for torch version < 2.7.0"
+ "Setting ignored_modules to None."
+ )
+ self.ignored_modules = None
+ # Single warning for all deprecation warnings due to FSDP2 conversion
+ if _fsdp2_warnings:
+ logger.warning("Multiple deprecation warnings due to FSDP2 conversion:\n".join(_fsdp2_warnings))
+
+ def set_state_dict_type(self, state_dict_type=None):
+ """
+ Set the state dict config based on the `StateDictType`.
+ """
+ from torch.distributed.fsdp.fully_sharded_data_parallel import (
+ FullOptimStateDictConfig,
+ FullStateDictConfig,
+ ShardedOptimStateDictConfig,
+ ShardedStateDictConfig,
+ StateDictType,
+ )
+
+ # Override the state_dict_type if provided, typical use case:
+ # user trains with sharded, but final save is with full
+ if state_dict_type is not None:
+ self.state_dict_type = state_dict_type
+
+ if self.state_dict_type is None:
+ self.state_dict_type = os.environ.get(
+ "FSDP_STATE_DICT_TYPE",
+ "FULL_STATE_DICT" if self.fsdp_version == 1 else "SHARDED_STATE_DICT",
+ )
+ if isinstance(self.state_dict_type, str):
+ if self.state_dict_type.isdigit():
+ self.state_dict_type = StateDictType(int(self.state_dict_type))
+ else:
+ self.state_dict_type = StateDictType[self.state_dict_type.upper()]
+
+ if self.state_dict_type == StateDictType.FULL_STATE_DICT:
+ if self.state_dict_config is None:
+ self.state_dict_config = FullStateDictConfig(offload_to_cpu=True, rank0_only=True)
+ if self.optim_state_dict_config is None:
+ self.optim_state_dict_config = FullOptimStateDictConfig(offload_to_cpu=True, rank0_only=True)
+ elif self.state_dict_type == StateDictType.SHARDED_STATE_DICT:
+ if self.state_dict_config is None:
+ self.state_dict_config = ShardedStateDictConfig(offload_to_cpu=True)
+ if self.optim_state_dict_config is None:
+ self.optim_state_dict_config = ShardedOptimStateDictConfig(offload_to_cpu=True)
+
+ if self.fsdp_version == 2 and self.state_dict_type == StateDictType.LOCAL_STATE_DICT:
+ raise ValueError(
+ "FSDP2 does not support LOCAL_STATE_DICT. "
+ "Please set `fsdp_state_dict_type` to `SHARDED_STATE_DICT` or `FULL_STATE_DICT`."
+ )
+
+ def set_auto_wrap_policy(self, model):
+ """
+ Given `model`, creates an `auto_wrap_policy` based on the passed in policy and if we can use the
+ `transformer_cls_to_wrap`
+ """
+ from torch.distributed.fsdp.wrap import (
+ size_based_auto_wrap_policy,
+ transformer_auto_wrap_policy,
+ )
+
+ # First base off of `_no_split_modules`
+ no_split_modules = getattr(model, "_no_split_modules", None)
+ default_transformer_cls_names_to_wrap = list(no_split_modules) if no_split_modules is not None else []
+ if self.auto_wrap_policy == transformer_auto_wrap_policy:
+ if self.transformer_cls_names_to_wrap is None:
+ self.transformer_cls_names_to_wrap = default_transformer_cls_names_to_wrap
+ transformer_cls_to_wrap = set()
+ for layer_class in self.transformer_cls_names_to_wrap:
+ transformer_cls = get_module_class_from_name(model, layer_class)
+ if transformer_cls is None:
+ raise ValueError(f"Could not find the transformer layer class {layer_class} in the model.")
+ transformer_cls_to_wrap.add(transformer_cls)
+ # Finally we set the auto_wrap_policy to a callable
+ self.auto_wrap_policy = functools.partial(
+ self.auto_wrap_policy, transformer_layer_cls=transformer_cls_to_wrap
+ )
+
+ elif self.auto_wrap_policy == size_based_auto_wrap_policy:
+ # If zero, we silently ignore it.
+ if self.min_num_params > 0:
+ self.auto_wrap_policy = functools.partial(self.auto_wrap_policy, min_num_params=self.min_num_params)
+ else:
+ self.auto_wrap_policy = None
+
+ def set_mixed_precision(self, mixed_precision, buffer_autocast=False, override=False):
+ "Sets the mixed precision policy for FSDP"
+ mixed_precision_mapping = {
+ "fp8": torch.bfloat16,
+ "fp16": torch.float16,
+ "bf16": torch.bfloat16,
+ "fp32": torch.float32,
+ }
+ dtype = mixed_precision
+ if isinstance(mixed_precision, str):
+ dtype = mixed_precision_mapping.get(mixed_precision, None)
+ if dtype is None:
+ raise ValueError(
+ f"Invalid mixed precision: {mixed_precision}. Must be one of {list(mixed_precision_mapping.keys())}"
+ )
+ elif isinstance(mixed_precision, torch.dtype) and mixed_precision not in mixed_precision_mapping.values():
+ raise ValueError(
+ f"Invalid mixed precision: {mixed_precision}. Must be one of {list(mixed_precision_mapping.values())}"
+ )
+
+ buffer_type = torch.float32 if buffer_autocast else dtype
+
+ if self.fsdp_version == 1:
+ from torch.distributed.fsdp import MixedPrecision
+ elif self.fsdp_version == 2:
+ from torch.distributed.fsdp import MixedPrecisionPolicy as MixedPrecision
+
+ if override or self.mixed_precision_policy is None:
+ dtype_args = {"param_dtype": dtype, "reduce_dtype": dtype}
+ if self.fsdp_version == 1:
+ dtype_args["buffer_dtype"] = buffer_type
+ else:
+ dtype_args["output_dtype"] = dtype
+ # TODO(s1ro1): `cast_forward_inputs` for FSDP2?
+ self.mixed_precision_policy = MixedPrecision(**dtype_args)
+ elif isinstance(self.mixed_precision_policy, dict):
+ # Check for incompatible types
+ valid_keys = ["param_dtype", "reduce_dtype"] + (
+ ["buffer_dtype"] if self.fsdp_version == 1 else ["output_dtype"]
+ )
+ missing_keys = [k for k in valid_keys if k not in self.mixed_precision_policy]
+ invalid_values = [
+ k for k, v in self.mixed_precision_policy.items() if v not in mixed_precision_mapping.values()
+ ]
+ if missing_keys or invalid_values:
+ raise ValueError(
+ f"Invalid mixed precision policy: {self.mixed_precision_policy}. "
+ f"Must be a `dict` with keys {valid_keys}."
+ f"Values must be one of {list(mixed_precision_mapping.values())}"
+ )
+ self.mixed_precision_policy = MixedPrecision(**self.mixed_precision_policy)
+
+ def validate_mixed_precision_policy(self):
+ """
+ Validates the mixed precision policy, abstracted away to not bring in the imports if not needed.
+ """
+ if self.fsdp_version == 2:
+ from torch.distributed.fsdp import MixedPrecisionPolicy as MixedPrecision
+ else:
+ from torch.distributed.fsdp import MixedPrecision
+
+ if not isinstance(self.mixed_precision_policy, MixedPrecision):
+ required_type = (
+ "`torch.distributed.fsdp.MixedPrecisionPolicy`"
+ if self.fsdp_version == 2
+ else "`torch.distributed.fsdp.MixedPrecision`"
+ )
+ raise ValueError(f"mixed_precision_policy must be an instance of {required_type}.")
+
+ def set_cpu_offload(self):
+ if self.fsdp_version == 2:
+ from torch.distributed.fsdp import CPUOffloadPolicy, OffloadPolicy
+ else:
+ from torch.distributed.fsdp import CPUOffload
+
+ if isinstance(self.cpu_offload, bool):
+ if self.fsdp_version == 2:
+ if not self.cpu_offload:
+ self.cpu_offload = OffloadPolicy()
+ else:
+ self.cpu_offload = CPUOffloadPolicy()
+ else:
+ self.cpu_offload = CPUOffload(offload_params=self.cpu_offload)
+
+ def validate_cpu_offload(self):
+ if self.fsdp_version == 2:
+ from torch.distributed.fsdp import OffloadPolicy
+ else:
+ from torch.distributed.fsdp import CPUOffload
+
+ if self.fsdp_version == 2 and not isinstance(self.cpu_offload, OffloadPolicy):
+ raise ValueError(
+ f"`cpu_offload` must be an instance of `torch.distributed.fsdp.OffloadPolicy` in FSDP2, got {self.cpu_offload}"
+ )
+ if self.fsdp_version == 1 and not isinstance(self.cpu_offload, CPUOffload):
+ raise ValueError(
+ f"`cpu_offload` must be an instance of `torch.distributed.fsdp.CPUOffload` in FSDP1, got {self.cpu_offload}"
+ )
+
+
+@dataclass
+class TorchTensorParallelPlugin:
+ """
+ This plugin is used to enable tensor parallelism using PyTorch >= 2.0.
+ """
+
+ tp_size: int = field(
+ default=1,
+ metadata={"help": "tensor parallel size will be used in the device mesh preparation"},
+ )
+
+ # torch_device_mesh is of type "torch.distributed.DeviceMesh"
+ torch_device_mesh: Optional["torch.distributed.DeviceMesh"] = field(default=None)
+
+
+@dataclass
+class TorchContextParallelConfig:
+ """
+ This class holds the configuration for context parallelism in PyTorch.
+ """
+
+ cp_comm_strategy: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": "Communication strategy for context parallelism. Can be one of 'allgather' or 'alltoall'. Defaults to 'allgather'."
+ },
+ )
+
+ def __post_init__(self):
+ if not is_torch_version(">=", BETA_CP_AVAILABLE_PYTORCH_VERSION):
+ raise ValueError(
+ f"FSDP2-based Context parallelism is only available in PyTorch {BETA_CP_AVAILABLE_PYTORCH_VERSION} and later versions. "
+ "Please upgrade your PyTorch version."
+ )
+
+ if self.cp_comm_strategy is None:
+ self.cp_comm_strategy = os.environ.get("PARALLELISM_CONFIG_CP_COMM_STRATEGY", "allgather")
+ if self.cp_comm_strategy not in ["allgather", "alltoall"]:
+ raise ValueError(
+ f"Invalid cp_comm_strategy: {self.cp_comm_strategy}. Must be one of 'allgather' or 'alltoall'."
+ )
+
+
+@dataclass
+class DeepSpeedSequenceParallelConfig:
+ sp_seq_length: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": "Sequence length for when batches are all of the same length. For variable sequence lengths across batches set `sp_seq_length_is_variable=True` and leave this field unset"
+ },
+ )
+ sp_seq_length_is_variable: Optional[bool] = field(
+ default=None,
+ metadata={
+ "help": "If `True` will work with a sequence length that may change between batches, in which case `sp_seq_length` value can be set to anything divisible by cp size or remain unset. If `False` then `sp_seq_length` needs to match the batch's sequence length dimension. The default is `True`."
+ },
+ )
+ sp_attn_implementation: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": "Attention implementation to use. Can be one of 'flash_attention_2', 'flash_attention_3' or 'sdpa'. Defaults to `sdpa`."
+ },
+ )
+
+ def __post_init__(self):
+ # sp_seq_length_is_variable and sp_seq_length are interconnected
+ if self.sp_seq_length_is_variable is None:
+ self.sp_seq_length_is_variable = (
+ os.environ.get("PARALLELISM_CONFIG_SP_SEQ_LENGTH_IS_VARIABLE", "true").lower() == "true"
+ )
+
+ if not self.sp_seq_length_is_variable and self.sp_seq_length is None:
+ if "PARALLELISM_CONFIG_SP_SEQ_LENGTH" not in os.environ:
+ raise ValueError(
+ "when `sp_seq_length_is_variable` is `False` `sp_seq_length` must be provided either through the constructor or the environment variable PARALLELISM_CONFIG_SP_SEQ_LENGTH"
+ )
+ else:
+ self.sp_seq_length = os.environ.get("PARALLELISM_CONFIG_SP_SEQ_LENGTH")
+ self.sp_seq_length = None if self.sp_seq_length == "None" else int(self.sp_seq_length)
+
+ if self.sp_attn_implementation is None:
+ self.sp_attn_implementation = os.environ.get("PARALLELISM_CONFIG_SP_ATTN_IMPLEMENTATION", None)
+
+ if self.sp_attn_implementation is not None and self.sp_attn_implementation not in [
+ "flash_attention_2",
+ "flash_attention_3",
+ "sdpa",
+ ]:
+ raise ValueError(
+ f"Invalid sp_attn_implementation: {self.sp_attn_implementation}. Must be one of 'flash_attention_2', 'flash_attention_3' or 'sdpa'."
+ )
+
+
+@dataclass
+class TorchTensorParallelConfig:
+ """
+ Use this object in your [`Accelerator`] to customize your torch tensor parallelism.
+ """
+
+ enable_async_tp: bool = False
+
+ def __post_init__(self):
+ if not is_torch_version(">=", BETA_TP_AVAILABLE_PYTORCH_VERSION):
+ raise ValueError(
+ f"Torch tensor parallelism is only available in PyTorch {BETA_TP_AVAILABLE_PYTORCH_VERSION} and later versions. "
+ "Please upgrade your PyTorch version."
+ )
+
+ if not compare_versions("transformers", ">=", BETA_TP_AVAILABLE_TRANSFORMERS_VERSION):
+ raise ValueError(f"TP requires transformers >= {BETA_TP_AVAILABLE_TRANSFORMERS_VERSION}")
+
+ if self.enable_async_tp:
+ warnings.warn("Async tensor parallelism is currently not supported, ignoring this option.")
+
+
+@dataclass
+class MegatronLMPlugin:
+ """
+ Plugin for Megatron-LM to enable tensor, pipeline, sequence and data parallelism. Also to enable selective
+ activation recomputation and optimized fused kernels.
+
+ Args:
+ tp_degree (`int`, defaults to `None`):
+ Tensor parallelism degree.
+ pp_degree (`int`, defaults to `None`):
+ Pipeline parallelism degree.
+ num_micro_batches (`int`, defaults to `None`):
+ Number of micro-batches.
+ gradient_clipping (`float`, defaults to `None`):
+ Gradient clipping value based on global L2 Norm (0 to disable).
+ sequence_parallelism (`bool`, defaults to `None`):
+ Enable sequence parallelism.
+ recompute_activations (`bool`, defaults to `None`):
+ Enable selective activation recomputation.
+ use_distributed_optimizr (`bool`, defaults to `None`):
+ Enable distributed optimizer.
+ pipeline_model_parallel_split_rank (`int`, defaults to `None`):
+ Rank where encoder and decoder should be split.
+ num_layers_per_virtual_pipeline_stage (`int`, defaults to `None`):
+ Number of layers per virtual pipeline stage.
+ is_train_batch_min (`str`, defaults to `True`):
+ If both tran & eval dataloaders are specified, this will decide the `micro_batch_size`.
+ train_iters (`int`, defaults to `None`):
+ Total number of samples to train over all training runs. Note that either train-iters or train-samples
+ should be provided when using `MegatronLMDummyScheduler`.
+ train_samples (`int`, defaults to `None`):
+ Total number of samples to train over all training runs. Note that either train-iters or train-samples
+ should be provided when using `MegatronLMDummyScheduler`.
+ weight_decay_incr_style (`str`, defaults to `'constant'`):
+ Weight decay increment function. choices=["constant", "linear", "cosine"].
+ start_weight_decay (`float`, defaults to `None`):
+ Initial weight decay coefficient for L2 regularization.
+ end_weight_decay (`float`, defaults to `None`):
+ End of run weight decay coefficient for L2 regularization.
+ lr_decay_style (`str`, defaults to `'linear'`):
+ Learning rate decay function. choices=['constant', 'linear', 'cosine'].
+ lr_decay_iters (`int`, defaults to `None`):
+ Number of iterations for learning rate decay. If None defaults to `train_iters`.
+ lr_decay_samples (`int`, defaults to `None`):
+ Number of samples for learning rate decay. If None defaults to `train_samples`.
+ lr_warmup_iters (`int`, defaults to `None`):
+ Number of iterations to linearly warmup learning rate over.
+ lr_warmup_samples (`int`, defaults to `None`):
+ Number of samples to linearly warmup learning rate over.
+ lr_warmup_fraction (`float`, defaults to `None`):
+ Fraction of lr-warmup-(iters/samples) to linearly warmup learning rate over.
+ min_lr (`float`, defaults to `0`):
+ Minimum value for learning rate. The scheduler clip values below this threshold.
+ consumed_samples (`List`, defaults to `None`):
+ Number of samples consumed in the same order as the dataloaders to `accelerator.prepare` call.
+ no_wd_decay_cond (`Optional`, defaults to `None`):
+ Condition to disable weight decay.
+ scale_lr_cond (`Optional`, defaults to `None`):
+ Condition to scale learning rate.
+ lr_mult (`float`, defaults to `1.0`):
+ Learning rate multiplier.
+ megatron_dataset_flag (`bool`, defaults to `False`):
+ Whether the format of dataset follows Megatron-LM Indexed/Cached/MemoryMapped format.
+ seq_length (`int`, defaults to `None`):
+ Maximum sequence length to process.
+ encoder_seq_length (`int`, defaults to `None`):
+ Maximum sequence length to process for the encoder.
+ decoder_seq_length (`int`, defaults to `None`):
+ Maximum sequence length to process for the decoder.
+ tensorboard_dir (`str`, defaults to `None`):
+ Path to save tensorboard logs.
+ set_all_logging_options (`bool`, defaults to `False`):
+ Whether to set all logging options.
+ eval_iters (`int`, defaults to `100`):
+ Number of iterations to run for evaluation validation/test for.
+ eval_interval (`int`, defaults to `1000`):
+ Interval between running evaluation on validation set.
+ return_logits (`bool`, defaults to `False`):
+ Whether to return logits from the model.
+ custom_train_step_class (`Optional`, defaults to `None`):
+ Custom train step class.
+ custom_train_step_kwargs (`Optional`, defaults to `None`):
+ Custom train step kwargs.
+ custom_model_provider_function (`Optional`, defaults to `None`):
+ Custom model provider function.
+ custom_prepare_model_function (`Optional`, defaults to `None`):
+ Custom prepare model function.
+ custom_megatron_datasets_provider_function (`Optional`, defaults to `None`):
+ Custom megatron train_valid_test datasets provider function.
+ custom_get_batch_function (`Optional`, defaults to `None`):
+ Custom get batch function.
+ custom_loss_function (`Optional`, defaults to `None`):
+ Custom loss function.
+ other_megatron_args (`Optional`, defaults to `None`):
+ Other Megatron-LM arguments. Please refer Megatron-LM.
+ """
+
+ tp_degree: int = field(default=None, metadata={"help": "tensor parallelism degree."})
+ pp_degree: int = field(default=None, metadata={"help": "pipeline parallelism degree."})
+ num_micro_batches: int = field(default=None, metadata={"help": "number of micro-batches."})
+ gradient_clipping: float = field(
+ default=None,
+ metadata={"help": "gradient clipping value based on global L2 Norm (0 to disable)"},
+ )
+ sequence_parallelism: bool = field(
+ default=None,
+ metadata={"help": "enable sequence parallelism"},
+ )
+ recompute_activations: bool = field(
+ default=None,
+ metadata={"help": "enable selective activation recomputation"},
+ )
+ use_distributed_optimizer: bool = field(
+ default=None,
+ metadata={"help": "enable distributed optimizer"},
+ )
+ pipeline_model_parallel_split_rank: int = field(
+ default=None,
+ metadata={"help": "Rank where encoder and decoder should be split."},
+ )
+ num_layers_per_virtual_pipeline_stage: int = field(
+ default=None, metadata={"help": "Number of layers per virtual pipeline stage."}
+ )
+ is_train_batch_min: str = field(
+ default=True,
+ metadata={"help": "If both train & eval dataloaders are specified, this will decide the micro_batch_size"},
+ )
+ train_iters: int = field(
+ default=None,
+ metadata={
+ "help": "Total number of iterations to train over all training runs. "
+ "Note that either train-iters or train-samples should be provided when using `MegatronLMDummyScheduler`"
+ },
+ )
+ train_samples: int = field(
+ default=None,
+ metadata={
+ "help": "Total number of samples to train over all training runs. "
+ "Note that either train-iters or train-samples should be provided when using `MegatronLMDummyScheduler`"
+ },
+ )
+ weight_decay_incr_style: str = field(
+ default="constant",
+ metadata={"help": 'Weight decay increment function. choices=["constant", "linear", "cosine"]. '},
+ )
+ start_weight_decay: float = field(
+ default=None,
+ metadata={"help": "Initial weight decay coefficient for L2 regularization."},
+ )
+ end_weight_decay: float = field(
+ default=None,
+ metadata={"help": "End of run weight decay coefficient for L2 regularization."},
+ )
+ lr_decay_style: str = field(
+ default="linear",
+ metadata={"help": "Learning rate decay function. choices=['constant', 'linear', 'cosine']."},
+ )
+ lr_decay_iters: int = field(
+ default=None,
+ metadata={"help": "Number of iterations for learning rate decay. If None defaults to `train_iters`."},
+ )
+ lr_decay_samples: int = field(
+ default=None,
+ metadata={"help": "Number of samples for learning rate decay. If None defaults to `train_samples`."},
+ )
+ lr_warmup_iters: int = field(
+ default=None,
+ metadata={"help": "number of iterations to linearly warmup learning rate over."},
+ )
+ lr_warmup_samples: int = field(
+ default=None,
+ metadata={"help": "number of samples to linearly warmup learning rate over."},
+ )
+ lr_warmup_fraction: float = field(
+ default=None,
+ metadata={"help": "fraction of lr-warmup-(iters/samples) to linearly warmup learning rate over."},
+ )
+ min_lr: float = field(
+ default=0,
+ metadata={"help": "Minimum value for learning rate. The scheduler clip values below this threshold."},
+ )
+ consumed_samples: list[int] = field(
+ default=None,
+ metadata={
+ "help": "Number of samples consumed in the same order as the dataloaders to `accelerator.prepare` call."
+ },
+ )
+ no_wd_decay_cond: Optional[Callable] = field(default=None, metadata={"help": "Condition to disable weight decay."})
+ scale_lr_cond: Optional[Callable] = field(default=None, metadata={"help": "Condition to scale learning rate."})
+ lr_mult: float = field(default=1.0, metadata={"help": "Learning rate multiplier."})
+ megatron_dataset_flag: bool = field(
+ default=False,
+ metadata={"help": "Whether the format of dataset follows Megatron-LM Indexed/Cached/MemoryMapped format."},
+ )
+ seq_length: int = field(
+ default=None,
+ metadata={"help": "Maximum sequence length to process."},
+ )
+ encoder_seq_length: int = field(
+ default=None,
+ metadata={"help": "Maximum sequence length to process for the encoder."},
+ )
+ decoder_seq_length: int = field(
+ default=None,
+ metadata={"help": "Maximum sequence length to process for the decoder."},
+ )
+ tensorboard_dir: str = field(
+ default=None,
+ metadata={"help": "Path to save tensorboard logs."},
+ )
+ set_all_logging_options: bool = field(
+ default=False,
+ metadata={"help": "Whether to set all logging options."},
+ )
+ eval_iters: int = field(
+ default=100,
+ metadata={"help": "Number of iterations to run for evaluation validation/test for."},
+ )
+ eval_interval: int = field(
+ default=1000,
+ metadata={"help": "Interval between running evaluation on validation set."},
+ )
+ return_logits: bool = field(
+ default=False,
+ metadata={"help": "Whether to return logits from the model."},
+ )
+
+ # custom train step args
+ custom_train_step_class: Optional[Any] = field(
+ default=None,
+ metadata={"help": "Custom train step class."},
+ )
+ custom_train_step_kwargs: Optional[dict[str, Any]] = field(
+ default=None,
+ metadata={"help": "Custom train step kwargs."},
+ )
+
+ # custom model args
+ custom_model_provider_function: Optional[Callable] = field(
+ default=None,
+ metadata={"help": "Custom model provider function."},
+ )
+ custom_prepare_model_function: Optional[Callable] = field(
+ default=None,
+ metadata={"help": "Custom prepare model function."},
+ )
+ custom_megatron_datasets_provider_function: Optional[Callable] = field(
+ default=None,
+ metadata={"help": "Custom megatron train_valid_test datasets provider function."},
+ )
+ custom_get_batch_function: Optional[Callable] = field(
+ default=None,
+ metadata={"help": "Custom get batch function."},
+ )
+ custom_loss_function: Optional[Callable] = field(
+ default=None,
+ metadata={"help": "Custom loss function."},
+ )
+
+ # remaining args such as enabling Alibi/ROPE positional embeddings,
+ # wandb logging, Multi-Query Attention, etc.
+ other_megatron_args: Optional[dict[str, Any]] = field(
+ default=None,
+ metadata={"help": "Other Megatron-LM arguments. Please refer Megatron-LM"},
+ )
+
+ def __post_init__(self):
+ prefix = "MEGATRON_LM_"
+ if self.tp_degree is None:
+ self.tp_degree = int(os.environ.get(prefix + "TP_DEGREE", 1))
+ if self.pp_degree is None:
+ self.pp_degree = int(os.environ.get(prefix + "PP_DEGREE", 1))
+ if self.num_micro_batches is None:
+ self.num_micro_batches = int(os.environ.get(prefix + "NUM_MICRO_BATCHES", 1))
+ if self.gradient_clipping is None:
+ self.gradient_clipping = float(os.environ.get(prefix + "GRADIENT_CLIPPING", 1.0))
+ if self.recompute_activations is None:
+ self.recompute_activations = str_to_bool(os.environ.get(prefix + "RECOMPUTE_ACTIVATIONS", "False")) == 1
+ if self.use_distributed_optimizer is None:
+ self.use_distributed_optimizer = (
+ str_to_bool(os.environ.get(prefix + "USE_DISTRIBUTED_OPTIMIZER", "False")) == 1
+ )
+ if self.sequence_parallelism is None:
+ self.sequence_parallelism = str_to_bool(os.environ.get(prefix + "SEQUENCE_PARALLELISM", "False")) == 1
+
+ if self.pp_degree > 1 or self.use_distributed_optimizer:
+ self.DDP_impl = "local"
+ else:
+ self.DDP_impl = "torch"
+
+ if self.consumed_samples is not None:
+ if len(self.consumed_samples) == 1:
+ self.consumed_samples.extend([0, 0])
+ elif len(self.consumed_samples) == 2:
+ self.consumed_samples.append(0)
+
+ self.megatron_lm_default_args = {
+ "tensor_model_parallel_size": self.tp_degree,
+ "pipeline_model_parallel_size": self.pp_degree,
+ "pipeline_model_parallel_split_rank": self.pipeline_model_parallel_split_rank,
+ "num_layers_per_virtual_pipeline_stage": self.num_layers_per_virtual_pipeline_stage,
+ "DDP_impl": self.DDP_impl,
+ "use_distributed_optimizer": self.use_distributed_optimizer,
+ "sequence_parallel": self.sequence_parallelism,
+ "clip_grad": self.gradient_clipping,
+ "num_micro_batches": self.num_micro_batches,
+ "consumed_samples": self.consumed_samples,
+ "no_wd_decay_cond": self.no_wd_decay_cond,
+ "scale_lr_cond": self.scale_lr_cond,
+ "lr_mult": self.lr_mult,
+ "megatron_dataset_flag": self.megatron_dataset_flag,
+ "eval_iters": self.eval_iters,
+ "eval_interval": self.eval_interval,
+ }
+ if self.recompute_activations:
+ self.megatron_lm_default_args["recompute_granularity"] = "selective"
+ if self.tensorboard_dir is not None:
+ self.megatron_lm_default_args["tensorboard_dir"] = self.tensorboard_dir
+ if self.set_all_logging_options:
+ self.set_tensorboard_logging_options()
+ if self.other_megatron_args is not None:
+ self.megatron_lm_default_args.update(self.other_megatron_args)
+
+ def set_network_size_args(self, model, batch_data=None):
+ model_config_type = model.config.model_type.lower()
+ for model_type in MODEL_CONFIGS_TO_MEGATRON_PARSERS.keys():
+ if model_type in model_config_type:
+ MODEL_CONFIGS_TO_MEGATRON_PARSERS[model_type](self, model, batch_data)
+ return
+ raise ValueError(
+ f"Accelerate Megatron-LM integration not supports {model_config_type} model. "
+ "You can add your own model config parser."
+ )
+
+ def set_mixed_precision(self, mixed_precision):
+ if mixed_precision == "fp16":
+ self.megatron_lm_default_args["fp16"] = True
+ elif mixed_precision == "bf16":
+ self.megatron_lm_default_args["bf16"] = True
+ self.DDP_impl = "local"
+ self.megatron_lm_default_args["DDP_impl"] = self.DDP_impl
+
+ def set_training_args(self, micro_batch_size, dp_degree):
+ self.data_parallel_size = dp_degree
+ self.micro_batch_size = micro_batch_size
+ self.global_batch_size = dp_degree * micro_batch_size * self.num_micro_batches
+ self.megatron_lm_default_args["data_parallel_size"] = self.data_parallel_size
+ self.megatron_lm_default_args["micro_batch_size"] = self.micro_batch_size
+ self.megatron_lm_default_args["global_batch_size"] = self.global_batch_size
+
+ def set_optimizer_type(self, optimizer):
+ optimizer_name = optimizer.__class__.__name__.lower()
+ if "adam" in optimizer_name:
+ self.megatron_lm_default_args["optimizer"] = "adam"
+ self.megatron_lm_default_args["adam_beta1"] = optimizer.defaults["betas"][0]
+ self.megatron_lm_default_args["adam_beta2"] = optimizer.defaults["betas"][1]
+ self.megatron_lm_default_args["adam_eps"] = optimizer.defaults["eps"]
+ elif "sgd" in optimizer_name:
+ self.megatron_lm_default_args["optimizer"] = "sgd"
+ self.megatron_lm_default_args["sgd_momentum"] = optimizer.defaults["momentum"]
+ else:
+ raise ValueError(f"Optimizer {optimizer_name} is not supported by Megatron-LM")
+
+ self.megatron_lm_default_args["lr"] = optimizer.defaults["lr"]
+ self.megatron_lm_default_args["weight_decay"] = optimizer.defaults["weight_decay"]
+
+ def set_scheduler_args(self, scheduler):
+ if self.train_iters is None:
+ self.train_iters = scheduler.total_num_steps // self.megatron_lm_default_args["data_parallel_size"]
+ if self.train_samples is not None:
+ self.train_samples = None
+ warnings.warn(
+ "Ignoring `train_samples` as `train_iters` based on scheduler is being used for training."
+ )
+ if self.lr_warmup_iters is None:
+ self.lr_warmup_iters = scheduler.warmup_num_steps // self.megatron_lm_default_args["data_parallel_size"]
+ if self.lr_warmup_samples is not None:
+ warnings.warn(
+ "Ignoring `lr_warmup_samples` as `lr_warmup_iters` based on scheduler is being used for training."
+ )
+ self.lr_warmup_samples = 0
+
+ self.megatron_lm_default_args["train_iters"] = self.train_iters
+ self.megatron_lm_default_args["lr_warmup_iters"] = self.lr_warmup_iters
+ self.megatron_lm_default_args["train_samples"] = self.train_samples
+ self.megatron_lm_default_args["lr_warmup_samples"] = self.lr_warmup_samples
+ self.megatron_lm_default_args["lr_decay_iters"] = self.lr_decay_iters
+ self.megatron_lm_default_args["lr_decay_samples"] = self.lr_decay_samples
+ self.megatron_lm_default_args["lr_warmup_fraction"] = self.lr_warmup_fraction
+ self.megatron_lm_default_args["lr_decay_style"] = self.lr_decay_style
+ self.megatron_lm_default_args["weight_decay_incr_style"] = self.weight_decay_incr_style
+ self.megatron_lm_default_args["start_weight_decay"] = self.start_weight_decay
+ self.megatron_lm_default_args["end_weight_decay"] = self.end_weight_decay
+ self.megatron_lm_default_args["min_lr"] = self.min_lr
+
+ def set_tensorboard_logging_options(self):
+ from megatron.training.arguments import _add_logging_args
+
+ parser = argparse.ArgumentParser()
+ parser = _add_logging_args(parser)
+ logging_args = parser.parse_known_args()
+ self.dataset_args = vars(logging_args[0])
+ for key, value in self.dataset_args.items():
+ if key.startswith("log_"):
+ self.megatron_lm_default_args[key] = True
+ elif key.startswith("no_log_"):
+ self.megatron_lm_default_args[key.replace("no_", "")] = True
+
+
+MODEL_CONFIGS_TO_MEGATRON_PARSERS = {}
+
+
+def add_model_config_to_megatron_parser(model_type: str):
+ def add_model_config_parser_helper(func):
+ @functools.wraps(func)
+ def wrapper(*args, **kwargs):
+ return func(*args, **kwargs)
+
+ MODEL_CONFIGS_TO_MEGATRON_PARSERS[model_type] = func
+ return wrapper
+
+ return add_model_config_parser_helper
+
+
+@add_model_config_to_megatron_parser("megatron-bert")
+def parse_bert_config(megatron_lm_plugin, model, batch_data):
+ model_type_name = "bert"
+ num_layers = model.config.num_hidden_layers
+ hidden_size = model.config.hidden_size
+ num_attention_heads = model.config.num_attention_heads
+ max_position_embeddings = model.config.max_position_embeddings
+ num_labels = model.config.num_labels
+ orig_vocab_size = model.config.vocab_size
+ pretraining_flag = False
+ if "maskedlm" in model.__class__.__name__.lower():
+ pretraining_flag = True
+ if megatron_lm_plugin.seq_length is not None:
+ if megatron_lm_plugin.encoder_seq_length is not None:
+ warnings.warn("Both `seq_length` and `encoder_seq_length` are set. Using `encoder_seq_length`.")
+ megatron_lm_plugin.seq_length = megatron_lm_plugin.encoder_seq_length
+ elif megatron_lm_plugin.encoder_seq_length is not None:
+ megatron_lm_plugin.seq_length = megatron_lm_plugin.encoder_seq_length
+ elif batch_data is not None:
+ megatron_lm_plugin.seq_length = batch_data["input_ids"].shape[1]
+ else:
+ megatron_lm_plugin.seq_length = max_position_embeddings
+ megatron_lm_plugin.megatron_lm_default_args["seq_length"] = megatron_lm_plugin.seq_length
+ megatron_lm_plugin.megatron_lm_default_args["model_type_name"] = model_type_name
+ megatron_lm_plugin.megatron_lm_default_args["num_layers"] = num_layers
+ megatron_lm_plugin.megatron_lm_default_args["hidden_size"] = hidden_size
+ megatron_lm_plugin.megatron_lm_default_args["num_attention_heads"] = num_attention_heads
+ megatron_lm_plugin.megatron_lm_default_args["max_position_embeddings"] = max_position_embeddings
+ megatron_lm_plugin.megatron_lm_default_args["pretraining_flag"] = pretraining_flag
+ megatron_lm_plugin.megatron_lm_default_args["orig_vocab_size"] = orig_vocab_size
+ megatron_lm_plugin.megatron_lm_default_args["model_return_dict"] = model.config.return_dict
+ megatron_lm_plugin.megatron_lm_default_args["num_labels"] = num_labels
+
+
+@add_model_config_to_megatron_parser("gpt2")
+def parse_gpt2_config(megatron_lm_plugin, model, batch_data):
+ model_type_name = "gpt"
+ num_layers = model.config.n_layer
+ hidden_size = model.config.n_embd
+ num_attention_heads = model.config.n_head
+ max_position_embeddings = model.config.n_positions
+ orig_vocab_size = model.config.vocab_size
+ pretraining_flag = True
+ if megatron_lm_plugin.seq_length is not None:
+ if megatron_lm_plugin.decoder_seq_length is not None:
+ warnings.warn("Both `seq_length` and `decoder_seq_length` are set. Using `decoder_seq_length`.")
+ megatron_lm_plugin.seq_length = megatron_lm_plugin.decoder_seq_length
+ elif megatron_lm_plugin.decoder_seq_length is not None:
+ megatron_lm_plugin.seq_length = megatron_lm_plugin.decoder_seq_length
+ elif batch_data is not None:
+ megatron_lm_plugin.seq_length = batch_data["input_ids"].shape[1]
+ else:
+ megatron_lm_plugin.seq_length = max_position_embeddings
+ megatron_lm_plugin.megatron_lm_default_args["seq_length"] = megatron_lm_plugin.seq_length
+ megatron_lm_plugin.megatron_lm_default_args["return_logits"] = megatron_lm_plugin.return_logits
+ megatron_lm_plugin.megatron_lm_default_args["tokenizer_type"] = "GPT2BPETokenizer"
+ megatron_lm_plugin.megatron_lm_default_args["model_type_name"] = model_type_name
+ megatron_lm_plugin.megatron_lm_default_args["num_layers"] = num_layers
+ megatron_lm_plugin.megatron_lm_default_args["hidden_size"] = hidden_size
+ megatron_lm_plugin.megatron_lm_default_args["num_attention_heads"] = num_attention_heads
+ megatron_lm_plugin.megatron_lm_default_args["max_position_embeddings"] = max_position_embeddings
+ megatron_lm_plugin.megatron_lm_default_args["pretraining_flag"] = pretraining_flag
+ megatron_lm_plugin.megatron_lm_default_args["orig_vocab_size"] = orig_vocab_size
+ megatron_lm_plugin.megatron_lm_default_args["model_return_dict"] = model.config.return_dict
+
+
+@add_model_config_to_megatron_parser("t5")
+def parse_t5_config(megatron_lm_plugin, model, batch_data):
+ model_type_name = "t5"
+ num_layers = model.config.num_layers
+ hidden_size = model.config.d_model
+ num_attention_heads = model.config.num_heads
+ max_position_embeddings = model.config.n_positions if hasattr(model.config, "n_positions") else 1024
+ orig_vocab_size = model.config.vocab_size
+ pretraining_flag = True
+ if megatron_lm_plugin.encoder_seq_length is None:
+ if batch_data is not None:
+ megatron_lm_plugin.encoder_seq_length = batch_data["input_ids"].shape[1]
+ else:
+ megatron_lm_plugin.encoder_seq_length = max_position_embeddings
+ if megatron_lm_plugin.decoder_seq_length is None:
+ if batch_data is not None:
+ megatron_lm_plugin.decoder_seq_length = batch_data["labels"].shape[1]
+ else:
+ megatron_lm_plugin.decoder_seq_length = max_position_embeddings
+ megatron_lm_plugin.megatron_lm_default_args["encoder_seq_length"] = megatron_lm_plugin.encoder_seq_length
+ megatron_lm_plugin.megatron_lm_default_args["decoder_seq_length"] = megatron_lm_plugin.decoder_seq_length
+ megatron_lm_plugin.megatron_lm_default_args["model_type_name"] = model_type_name
+ megatron_lm_plugin.megatron_lm_default_args["num_layers"] = num_layers
+ megatron_lm_plugin.megatron_lm_default_args["hidden_size"] = hidden_size
+ megatron_lm_plugin.megatron_lm_default_args["num_attention_heads"] = num_attention_heads
+ megatron_lm_plugin.megatron_lm_default_args["max_position_embeddings"] = max_position_embeddings
+ megatron_lm_plugin.megatron_lm_default_args["pretraining_flag"] = pretraining_flag
+ megatron_lm_plugin.megatron_lm_default_args["orig_vocab_size"] = orig_vocab_size
+ megatron_lm_plugin.megatron_lm_default_args["model_return_dict"] = model.config.return_dict
+
+
+@add_model_config_to_megatron_parser("llama")
+def parse_llama_config(megatron_lm_plugin, model, batch_data):
+ model_type_name = "gpt"
+ num_layers = model.config.num_hidden_layers
+ pretraining_flag = True
+ hidden_size = model.config.hidden_size
+ num_attention_heads = model.config.num_attention_heads
+ orig_vocab_size = model.config.vocab_size
+
+ max_position_embeddings = model.config.max_position_embeddings
+ seq_length = getattr(model.config, "max_sequence_length", None)
+ if megatron_lm_plugin.seq_length is None:
+ if seq_length is not None:
+ megatron_lm_plugin.seq_length = seq_length
+ elif megatron_lm_plugin.decoder_seq_length is not None:
+ megatron_lm_plugin.seq_length = megatron_lm_plugin.decoder_seq_length
+ elif batch_data is not None:
+ megatron_lm_plugin.seq_length = batch_data["input_ids"].shape[1]
+ else:
+ megatron_lm_plugin.seq_length = max_position_embeddings
+
+ megatron_lm_plugin.megatron_lm_default_args["return_logits"] = megatron_lm_plugin.return_logits
+ megatron_lm_plugin.megatron_lm_default_args["tokenizer_type"] = "Llama2Tokenizer"
+ megatron_lm_plugin.megatron_lm_default_args["model_type_name"] = model_type_name
+ megatron_lm_plugin.megatron_lm_default_args["num_layers"] = num_layers
+ megatron_lm_plugin.megatron_lm_default_args["pretraining_flag"] = pretraining_flag
+ megatron_lm_plugin.megatron_lm_default_args["hidden_size"] = hidden_size
+ megatron_lm_plugin.megatron_lm_default_args["num_attention_heads"] = num_attention_heads
+ megatron_lm_plugin.megatron_lm_default_args["orig_vocab_size"] = orig_vocab_size
+ megatron_lm_plugin.megatron_lm_default_args["max_position_embeddings"] = max_position_embeddings
+ megatron_lm_plugin.megatron_lm_default_args["seq_length"] = megatron_lm_plugin.seq_length
+ megatron_lm_plugin.megatron_lm_default_args["model_return_dict"] = model.config.return_dict
+
+
+@dataclass
+class BnbQuantizationConfig:
+ """
+ A plugin to enable BitsAndBytes 4bit and 8bit quantization
+
+ Args:
+ load_in_8bit (`bool`, defaults to `False`):
+ Enable 8bit quantization.
+ llm_int8_threshold (`float`, defaults to `6.0`):
+ Value of the outliner threshold. Only relevant when `load_in_8bit=True`.
+ load_in_4bit (`bool`, defaults to `False`):
+ Enable 4bit quantization.
+ bnb_4bit_quant_type (`str`, defaults to `fp4`):
+ Set the quantization data type in the `bnb.nn.Linear4Bit` layers. Options are {'fp4','np4'}.
+ bnb_4bit_use_double_quant (`bool`, defaults to `False`):
+ Enable nested quantization where the quantization constants from the first quantization are quantized
+ again.
+ bnb_4bit_compute_dtype (`bool`, defaults to `fp16`):
+ This sets the computational type which might be different than the input time. For example, inputs might be
+ fp32, but computation can be set to bf16 for speedups. Options are {'fp32','fp16','bf16'}.
+ torch_dtype (`torch.dtype`, defaults to `None`):
+ This sets the dtype of the remaining non quantized layers. `bitsandbytes` library suggests to set the value
+ to `torch.float16` for 8 bit model and use the same dtype as the compute dtype for 4 bit model.
+ skip_modules (`List[str]`, defaults to `None`):
+ An explicit list of the modules that we don't quantize. The dtype of these modules will be `torch_dtype`.
+ keep_in_fp32_modules (`List`, defaults to `None`):
+ An explicit list of the modules that we don't quantize. We keep them in `torch.float32`.
+ """
+
+ load_in_8bit: bool = field(default=False, metadata={"help": "enable 8bit quantization."})
+
+ llm_int8_threshold: float = field(
+ default=6.0,
+ metadata={"help": "value of the outliner threshold. only relevant when load_in_8bit=True"},
+ )
+
+ load_in_4bit: bool = field(default=False, metadata={"help": "enable 4bit quantization."})
+
+ bnb_4bit_quant_type: str = field(
+ default="fp4",
+ metadata={
+ "help": "set the quantization data type in the `bnb.nn.Linear4Bit` layers. Options are {'fp4','nf4'}."
+ },
+ )
+
+ bnb_4bit_use_double_quant: bool = field(
+ default=False,
+ metadata={
+ "help": "enable nested quantization where the quantization constants from the first quantization are quantized again."
+ },
+ )
+
+ bnb_4bit_compute_dtype: str = field(
+ default="fp16",
+ metadata={
+ "help": "This sets the computational type which might be different than the input time. For example, inputs might be "
+ "fp32, but computation can be set to bf16 for speedups. Options are {'fp32','fp16','bf16'}."
+ },
+ )
+
+ torch_dtype: torch.dtype = field(
+ default=None,
+ metadata={
+ "help": "this sets the dtype of the remaining non quantized layers. `bitsandbytes` library suggests to set the value"
+ "to `torch.float16` for 8 bit model and use the same dtype as the compute dtype for 4 bit model "
+ },
+ )
+
+ skip_modules: list[str] = field(
+ default=None,
+ metadata={
+ "help": "an explicit list of the modules that we don't quantize. The dtype of these modules will be `torch_dtype`."
+ },
+ )
+
+ keep_in_fp32_modules: list[str] = field(
+ default=None,
+ metadata={"help": "an explicit list of the modules that we don't quantize. We keep them in `torch.float32`."},
+ )
+
+ def __post_init__(self):
+ """
+ Safety checker that arguments are correct - also replaces some NoneType arguments with their default values.
+ """
+ if not isinstance(self.load_in_8bit, bool):
+ raise ValueError("load_in_8bit must be a boolean")
+
+ if not isinstance(self.load_in_4bit, bool):
+ raise ValueError("load_in_4bit must be a boolean")
+
+ if self.load_in_4bit and self.load_in_8bit:
+ raise ValueError("load_in_4bit and load_in_8bit can't be both True")
+
+ if not self.load_in_4bit and not self.load_in_8bit:
+ raise ValueError("load_in_4bit and load_in_8bit can't be both False")
+
+ if not isinstance(self.llm_int8_threshold, (int, float)):
+ raise ValueError("llm_int8_threshold must be a float or an int")
+
+ if not isinstance(self.bnb_4bit_quant_type, str):
+ raise ValueError("bnb_4bit_quant_type must be a string")
+ elif self.bnb_4bit_quant_type not in ["fp4", "nf4"]:
+ raise ValueError(f"bnb_4bit_quant_type must be in ['fp4','nf4'] but found {self.bnb_4bit_quant_type}")
+
+ if not isinstance(self.bnb_4bit_use_double_quant, bool):
+ raise ValueError("bnb_4bit_use_double_quant must be a boolean")
+
+ if isinstance(self.bnb_4bit_compute_dtype, str):
+ if self.bnb_4bit_compute_dtype == "fp32":
+ self.bnb_4bit_compute_dtype = torch.float32
+ elif self.bnb_4bit_compute_dtype == "fp16":
+ self.bnb_4bit_compute_dtype = torch.float16
+ elif self.bnb_4bit_compute_dtype == "bf16":
+ self.bnb_4bit_compute_dtype = torch.bfloat16
+ else:
+ raise ValueError(
+ f"bnb_4bit_compute_dtype must be in ['fp32','fp16','bf16'] but found {self.bnb_4bit_compute_dtype}"
+ )
+ elif not isinstance(self.bnb_4bit_compute_dtype, torch.dtype):
+ raise ValueError("bnb_4bit_compute_dtype must be a string or a torch.dtype")
+
+ if self.skip_modules is not None and not isinstance(self.skip_modules, list):
+ raise ValueError("skip_modules must be a list of strings")
+
+ if self.keep_in_fp32_modules is not None and not isinstance(self.keep_in_fp32_modules, list):
+ raise ValueError("keep_in_fp_32_modules must be a list of strings")
+
+ if self.load_in_4bit:
+ self.target_dtype = CustomDtype.INT4
+
+ if self.load_in_8bit:
+ self.target_dtype = torch.int8
+
+ if self.load_in_4bit and self.llm_int8_threshold != 6.0:
+ warnings.warn("llm_int8_threshold can only be used for model loaded in 8bit")
+
+ if isinstance(self.torch_dtype, str):
+ if self.torch_dtype == "fp32":
+ self.torch_dtype = torch.float32
+ elif self.torch_dtype == "fp16":
+ self.torch_dtype = torch.float16
+ elif self.torch_dtype == "bf16":
+ self.torch_dtype = torch.bfloat16
+ else:
+ raise ValueError(f"torch_dtype must be in ['fp32','fp16','bf16'] but found {self.torch_dtype}")
+ if self.load_in_8bit and self.torch_dtype is None:
+ self.torch_dtype = torch.float16
+
+ if self.load_in_4bit and self.torch_dtype is None:
+ self.torch_dtype = self.bnb_4bit_compute_dtype
+
+ if not isinstance(self.torch_dtype, torch.dtype):
+ raise ValueError("torch_dtype must be a torch.dtype")
+
+
+def get_module_class_from_name(module, name):
+ """
+ Gets a class from a module by its name.
+
+ Args:
+ module (`torch.nn.Module`): The module to get the class from.
+ name (`str`): The name of the class.
+ """
+ modules_children = list(module.children())
+ if module.__class__.__name__ == name:
+ return module.__class__
+ elif len(modules_children) == 0:
+ return
+ else:
+ for child_module in modules_children:
+ module_class = get_module_class_from_name(child_module, name)
+ if module_class is not None:
+ return module_class
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/deepspeed.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/deepspeed.py
new file mode 100644
index 0000000000000000000000000000000000000000..22db891c63d9bd48691acd87a15a206c270017a9
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/deepspeed.py
@@ -0,0 +1,385 @@
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import base64
+import json
+import os
+from copy import deepcopy
+
+from torch import optim
+
+from ..optimizer import AcceleratedOptimizer
+from ..scheduler import AcceleratedScheduler
+from .dataclasses import DistributedType
+from .imports import is_bnb_available
+from .versions import compare_versions
+
+
+def map_pytorch_optim_to_deepspeed(optimizer):
+ """
+ Args:
+ optimizer: torch.optim.Optimizer
+
+ Returns the DeepSeedCPUOptimizer (deepspeed.ops) version of the optimizer.
+ """
+
+ defaults = {k: v for k, v in optimizer.defaults.items() if k in ["lr", "weight_decay"]}
+
+ # Select the DeepSpeedCPUOptimizer based on the original optimizer class.
+ # DeepSpeedCPUAdam is the default
+ from deepspeed.ops.adam import DeepSpeedCPUAdam
+
+ optimizer_class = DeepSpeedCPUAdam
+
+ # For DeepSpeedCPUAdam (adamw_mode)
+ if compare_versions("deepspeed", ">=", "0.3.1"):
+ defaults["adamw_mode"] = False
+ is_adaw = isinstance(optimizer, optim.AdamW)
+
+ if is_bnb_available() and not is_adaw:
+ import bitsandbytes.optim as bnb_opt
+
+ if isinstance(optimizer, (bnb_opt.AdamW, bnb_opt.AdamW32bit)):
+ try:
+ is_adaw = optimizer.optim_bits == 32
+ except AttributeError:
+ is_adaw = optimizer.args.optim_bits == 32
+ else:
+ is_adaw = False
+
+ if is_adaw:
+ defaults["adamw_mode"] = True
+
+ # For DeepSpeedCPUAdagrad
+ if compare_versions("deepspeed", ">=", "0.5.5"):
+ # Check if the optimizer is PyTorch's Adagrad.
+ is_ada = isinstance(optimizer, optim.Adagrad)
+ # If not, and bitsandbytes is available,
+ # # check if the optimizer is the 32-bit bitsandbytes Adagrad.
+ if is_bnb_available() and not is_ada:
+ import bitsandbytes.optim as bnb_opt
+
+ if isinstance(optimizer, (bnb_opt.Adagrad, bnb_opt.Adagrad32bit)):
+ try:
+ is_ada = optimizer.optim_bits == 32
+ except AttributeError:
+ is_ada = optimizer.args.optim_bits == 32
+ if is_ada:
+ from deepspeed.ops.adagrad import DeepSpeedCPUAdagrad
+
+ optimizer_class = DeepSpeedCPUAdagrad
+
+ # For DeepSpeedCPULion
+ if is_bnb_available(min_version="0.38.0") and compare_versions("deepspeed", ">=", "0.11.0"):
+ from bitsandbytes.optim import Lion, Lion32bit
+
+ if isinstance(optimizer, (Lion, Lion32bit)):
+ try:
+ is_bnb_32bits = optimizer.optim_bits == 32
+ except AttributeError:
+ is_bnb_32bits = optimizer.args.optim_bits == 32
+ if is_bnb_32bits:
+ from deepspeed.ops.lion import DeepSpeedCPULion
+
+ optimizer_class = DeepSpeedCPULion
+
+ return optimizer_class(optimizer.param_groups, **defaults)
+
+
+def get_active_deepspeed_plugin(state):
+ """
+ Returns the currently active DeepSpeedPlugin.
+
+ Raises:
+ ValueError: If DeepSpeed was not enabled and this function is called.
+ """
+ if state.distributed_type != DistributedType.DEEPSPEED:
+ raise ValueError(
+ "Couldn't retrieve the active `DeepSpeedPlugin` as none were enabled. "
+ "Please make sure that either `Accelerator` is configured for `deepspeed` "
+ "or make sure that the desired `DeepSpeedPlugin` has been enabled (`AcceleratorState().select_deepspeed_plugin(name)`) "
+ "before calling this function."
+ )
+ if not isinstance(state.deepspeed_plugins, dict):
+ return state.deepspeed_plugins
+ return next(plugin for plugin in state.deepspeed_plugins.values() if plugin.selected)
+
+
+class HfDeepSpeedConfig:
+ """
+ This object contains a DeepSpeed configuration dictionary and can be quickly queried for things like zero stage.
+
+ A `weakref` of this object is stored in the module's globals to be able to access the config from areas where
+ things like the Trainer object is not available (e.g. `from_pretrained` and `_get_resized_embeddings`). Therefore
+ it's important that this object remains alive while the program is still running.
+
+ [`Trainer`] uses the `HfTrainerDeepSpeedConfig` subclass instead. That subclass has logic to sync the configuration
+ with values of [`TrainingArguments`] by replacing special placeholder values: `"auto"`. Without this special logic
+ the DeepSpeed configuration is not modified in any way.
+
+ Args:
+ config_file_or_dict (`Union[str, Dict]`): path to DeepSpeed config file or dict.
+
+ """
+
+ def __init__(self, config_file_or_dict):
+ if isinstance(config_file_or_dict, dict):
+ # Don't modify user's data should they want to reuse it (e.g. in tests), because once we
+ # modified it, it will not be accepted here again, since `auto` values would have been overridden
+ config = deepcopy(config_file_or_dict)
+ elif os.path.exists(config_file_or_dict):
+ with open(config_file_or_dict, encoding="utf-8") as f:
+ config = json.load(f)
+ else:
+ try:
+ try:
+ # First try parsing as JSON directly
+ config = json.loads(config_file_or_dict)
+ except json.JSONDecodeError:
+ # If that fails, try base64 decoding
+ config_decoded = base64.urlsafe_b64decode(config_file_or_dict).decode("utf-8")
+ config = json.loads(config_decoded)
+ except (UnicodeDecodeError, AttributeError, ValueError):
+ raise ValueError(
+ f"Expected a string path to an existing deepspeed config, or a dictionary, or a base64 encoded string. Received: {config_file_or_dict}"
+ )
+
+ self.config = config
+
+ self.set_stage_and_offload()
+
+ def set_stage_and_offload(self):
+ # zero stage - this is done as early as possible, before model is created, to allow
+ # ``is_deepspeed_zero3_enabled`` query and getting to the early deepspeed config object
+ # during ``zero.Init()`` which needs to know the dtype, and some other hparams.
+ self._stage = self.get_value("zero_optimization.stage", -1)
+
+ # offload
+ self._offload = False
+ if self.is_zero2() or self.is_zero3():
+ offload_devices_valid = set(["cpu", "nvme"])
+ offload_devices = set(
+ [
+ self.get_value("zero_optimization.offload_optimizer.device"),
+ self.get_value("zero_optimization.offload_param.device"),
+ ]
+ )
+ if len(offload_devices & offload_devices_valid) > 0:
+ self._offload = True
+
+ def find_config_node(self, ds_key_long):
+ config = self.config
+
+ # find the config node of interest if it exists
+ nodes = ds_key_long.split(".")
+ ds_key = nodes.pop()
+ for node in nodes:
+ config = config.get(node)
+ if config is None:
+ return None, ds_key
+
+ return config, ds_key
+
+ def get_value(self, ds_key_long, default=None):
+ """
+ Returns the set value or `default` if no value is set
+ """
+ config, ds_key = self.find_config_node(ds_key_long)
+ if config is None:
+ return default
+ return config.get(ds_key, default)
+
+ def del_config_sub_tree(self, ds_key_long, must_exist=False):
+ """
+ Deletes a sub-section of the config file if it's found.
+
+ Unless `must_exist` is `True` the section doesn't have to exist.
+ """
+ config = self.config
+
+ # find the config node of interest if it exists
+ nodes = ds_key_long.split(".")
+ for node in nodes:
+ parent_config = config
+ config = config.get(node)
+ if config is None:
+ if must_exist:
+ raise ValueError(f"Can't find {ds_key_long} entry in the config: {self.config}")
+ else:
+ return
+
+ # if found remove it
+ if parent_config is not None:
+ parent_config.pop(node)
+
+ def is_true(self, ds_key_long):
+ """
+ Returns `True`/``False` only if the value is set, always `False` otherwise. So use this method to ask the very
+ specific question of whether the value is set to `True` (and it's not set to `False`` or isn't set).
+
+ """
+ value = self.get_value(ds_key_long)
+ return False if value is None else bool(value)
+
+ def is_false(self, ds_key_long):
+ """
+ Returns `True`/``False` only if the value is set, always `False` otherwise. So use this method to ask the very
+ specific question of whether the value is set to `False` (and it's not set to `True`` or isn't set).
+ """
+ value = self.get_value(ds_key_long)
+ return False if value is None else not bool(value)
+
+ def is_zero2(self):
+ return self._stage == 2
+
+ def is_zero3(self):
+ return self._stage == 3
+
+ def is_offload(self):
+ return self._offload
+
+
+class DeepSpeedEngineWrapper:
+ """
+ Internal wrapper for deepspeed.runtime.engine.DeepSpeedEngine. This is used to follow conventional training loop.
+
+ Args:
+ engine (deepspeed.runtime.engine.DeepSpeedEngine): deepspeed engine to wrap
+ """
+
+ def __init__(self, engine):
+ self.engine = engine
+
+ def backward(self, loss, sync_gradients=True, **kwargs):
+ # Set gradient accumulation boundary based on Accelerate's sync_gradients state
+ # This tells DeepSpeed whether this is the final micro-batch before gradient sync
+ self.engine.set_gradient_accumulation_boundary(is_boundary=sync_gradients)
+
+ # runs backpropagation and handles mixed precision
+ self.engine.backward(loss, **kwargs)
+
+ # Only perform step and related operations at gradient accumulation boundaries
+ if sync_gradients:
+ # Deepspeed's `engine.step` performs the following operations:
+ # - gradient accumulation check
+ # - gradient clipping
+ # - optimizer step
+ # - zero grad
+ # - checking overflow
+ # - lr_scheduler step (only if engine.lr_scheduler is not None)
+ self.engine.step()
+ # and this plugin overrides the above calls with no-ops when Accelerate runs under
+ # Deepspeed, but allows normal functionality for non-Deepspeed cases thus enabling a simple
+ # training loop that works transparently under many training regimes.
+
+ def get_global_grad_norm(self):
+ """Get the global gradient norm from DeepSpeed engine."""
+ grad_norm = self.engine.get_global_grad_norm()
+ # Convert to scalar if it's a tensor
+ if hasattr(grad_norm, "item"):
+ return grad_norm.item()
+ return grad_norm
+
+
+class DeepSpeedOptimizerWrapper(AcceleratedOptimizer):
+ """
+ Internal wrapper around a deepspeed optimizer.
+
+ Args:
+ optimizer (`torch.optim.optimizer.Optimizer`):
+ The optimizer to wrap.
+ """
+
+ def __init__(self, optimizer):
+ super().__init__(optimizer, device_placement=False, scaler=None)
+ self.__has_overflow__ = hasattr(self.optimizer, "overflow")
+
+ def zero_grad(self, set_to_none=None):
+ pass # `accelerator.backward(loss)` is doing that automatically. Therefore, its implementation is not needed
+
+ def step(self):
+ pass # `accelerator.backward(loss)` is doing that automatically. Therefore, its implementation is not needed
+
+ @property
+ def step_was_skipped(self):
+ """Whether or not the optimizer step was done, or skipped because of gradient overflow."""
+ if self.__has_overflow__:
+ return self.optimizer.overflow
+ return False
+
+
+class DeepSpeedSchedulerWrapper(AcceleratedScheduler):
+ """
+ Internal wrapper around a deepspeed scheduler.
+
+ Args:
+ scheduler (`torch.optim.lr_scheduler.LambdaLR`):
+ The scheduler to wrap.
+ optimizers (one or a list of `torch.optim.Optimizer`):
+ """
+
+ def __init__(self, scheduler, optimizers):
+ super().__init__(scheduler, optimizers)
+
+ def step(self):
+ pass # `accelerator.backward(loss)` is doing that automatically. Therefore, its implementation is not needed
+
+
+class DummyOptim:
+ """
+ Dummy optimizer presents model parameters or param groups, this is primarily used to follow conventional training
+ loop when optimizer config is specified in the deepspeed config file.
+
+ Args:
+ lr (float):
+ Learning rate.
+ params (iterable): iterable of parameters to optimize or dicts defining
+ parameter groups
+ weight_decay (float):
+ Weight decay.
+ **kwargs (additional keyword arguments, *optional*):
+ Other arguments.
+ """
+
+ def __init__(self, params, lr=0.001, weight_decay=0, **kwargs):
+ self.params = params
+ self.lr = lr
+ self.weight_decay = weight_decay
+ self.kwargs = kwargs
+
+
+class DummyScheduler:
+ """
+ Dummy scheduler presents model parameters or param groups, this is primarily used to follow conventional training
+ loop when scheduler config is specified in the deepspeed config file.
+
+ Args:
+ optimizer (`torch.optim.optimizer.Optimizer`):
+ The optimizer to wrap.
+ total_num_steps (int, *optional*):
+ Total number of steps.
+ warmup_num_steps (int, *optional*):
+ Number of steps for warmup.
+ lr_scheduler_callable (callable, *optional*):
+ A callable function that creates an LR Scheduler. It accepts only one argument `optimizer`.
+ **kwargs (additional keyword arguments, *optional*):
+ Other arguments.
+ """
+
+ def __init__(self, optimizer, total_num_steps=None, warmup_num_steps=0, lr_scheduler_callable=None, **kwargs):
+ self.optimizer = optimizer
+ self.total_num_steps = total_num_steps
+ self.warmup_num_steps = warmup_num_steps
+ self.lr_scheduler_callable = lr_scheduler_callable
+ self.kwargs = kwargs
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/environment.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/environment.py
new file mode 100644
index 0000000000000000000000000000000000000000..faa3be2d336ad8674fdbdfd3d5504645b25f2b79
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/environment.py
@@ -0,0 +1,471 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import logging
+import math
+import os
+import platform
+import subprocess
+import sys
+from contextlib import contextmanager
+from dataclasses import dataclass, field
+from functools import lru_cache, wraps
+from shutil import which
+from typing import Optional, Union
+
+import torch
+from packaging.version import parse
+
+
+logger = logging.getLogger(__name__)
+
+
+def convert_dict_to_env_variables(current_env: dict):
+ """
+ Verifies that all keys and values in `current_env` do not contain illegal keys or values, and returns a list of
+ strings as the result.
+
+ Example:
+ ```python
+ >>> from accelerate.utils.environment import verify_env
+
+ >>> env = {"ACCELERATE_DEBUG_MODE": "1", "BAD_ENV_NAME": ">> valid_env_items = verify_env(env)
+ >>> print(valid_env_items)
+ ["ACCELERATE_DEBUG_MODE=1\n", "OTHER_ENV=2\n"]
+ ```
+ """
+ forbidden_chars = [";", "\n", "<", ">", " "]
+ valid_env_items = []
+ for key, value in current_env.items():
+ if all(char not in (key + value) for char in forbidden_chars) and len(key) >= 1 and len(value) >= 1:
+ valid_env_items.append(f"{key}={value}\n")
+ else:
+ logger.warning(f"WARNING: Skipping {key}={value} as it contains forbidden characters or missing values.")
+ return valid_env_items
+
+
+def str_to_bool(value, to_bool: bool = False) -> Union[int, bool]:
+ """
+ Converts a string representation of truth to `True` (1) or `False` (0).
+
+ True values are `y`, `yes`, `t`, `true`, `on`, and `1`; False value are `n`, `no`, `f`, `false`, `off`, and `0`;
+ """
+ value = value.lower()
+ if value in ("y", "yes", "t", "true", "on", "1"):
+ return 1 if not to_bool else True
+ elif value in ("n", "no", "f", "false", "off", "0"):
+ return 0 if not to_bool else False
+ else:
+ raise ValueError(f"invalid truth value {value}")
+
+
+def get_int_from_env(env_keys, default):
+ """Returns the first positive env value found in the `env_keys` list or the default."""
+ for e in env_keys:
+ val = int(os.environ.get(e, -1))
+ if val >= 0:
+ return val
+ return default
+
+
+def parse_flag_from_env(key, default=False):
+ """Returns truthy value for `key` from the env if available else the default."""
+ value = os.environ.get(key, str(default))
+ return str_to_bool(value) == 1 # As its name indicates `str_to_bool` actually returns an int...
+
+
+def parse_choice_from_env(key, default="no"):
+ value = os.environ.get(key, str(default))
+ return value
+
+
+def are_libraries_initialized(*library_names: str) -> list[str]:
+ """
+ Checks if any of `library_names` are imported in the environment. Will return any names that are.
+ """
+ return [lib_name for lib_name in library_names if lib_name in sys.modules.keys()]
+
+
+def get_current_device_type() -> tuple[str, str]:
+ """
+ Determines the current device type and distributed type without initializing any device.
+
+ This is particularly important when using fork-based multiprocessing, as device initialization
+ before forking can cause errors.
+
+ The device detection order follows the same priority as state.py:_prepare_backend():
+ MLU -> SDAA -> MUSA -> NPU -> HPU -> CUDA -> XPU
+
+ Returns:
+ tuple[str, str]: A tuple of (device_type, distributed_type)
+ - device_type: The device string (e.g., "cuda", "npu", "xpu")
+ - distributed_type: The distributed type string (e.g., "MULTI_GPU", "MULTI_NPU")
+
+ Example:
+ ```python
+ >>> device_type, distributed_type = get_current_device_type()
+ >>> print(device_type) # "cuda"
+ >>> print(distributed_type) # "MULTI_GPU"
+ ```
+ """
+ from .imports import (
+ is_hpu_available,
+ is_mlu_available,
+ is_musa_available,
+ is_npu_available,
+ is_sdaa_available,
+ is_xpu_available,
+ )
+
+ if is_mlu_available():
+ return "mlu", "MULTI_MLU"
+ elif is_sdaa_available():
+ return "sdaa", "MULTI_SDAA"
+ elif is_musa_available():
+ return "musa", "MULTI_MUSA"
+ elif is_npu_available():
+ return "npu", "MULTI_NPU"
+ elif is_hpu_available():
+ return "hpu", "MULTI_HPU"
+ elif torch.cuda.is_available():
+ return "cuda", "MULTI_GPU"
+ elif is_xpu_available():
+ return "xpu", "MULTI_XPU"
+ else:
+ # Default to CUDA even if not available (for CPU-only scenarios where CUDA code paths are still used)
+ return "cuda", "MULTI_GPU"
+
+
+def _nvidia_smi():
+ """
+ Returns the right nvidia-smi command based on the system.
+ """
+ if platform.system() == "Windows":
+ # If platform is Windows and nvidia-smi can't be found in path
+ # try from systemd drive with default installation path
+ command = which("nvidia-smi")
+ if command is None:
+ command = f"{os.environ['systemdrive']}\\Program Files\\NVIDIA Corporation\\NVSMI\\nvidia-smi.exe"
+ else:
+ command = "nvidia-smi"
+ return command
+
+
+def get_gpu_info():
+ """
+ Gets GPU count and names using `nvidia-smi` instead of torch to not initialize CUDA.
+
+ Largely based on the `gputil` library.
+ """
+ # Returns as list of `n` GPUs and their names
+ output = subprocess.check_output(
+ [_nvidia_smi(), "--query-gpu=count,name", "--format=csv,noheader"], universal_newlines=True
+ )
+ output = output.strip()
+ gpus = output.split(os.linesep)
+ # Get names from output
+ gpu_count = len(gpus)
+ gpu_names = [gpu.split(",")[1].strip() for gpu in gpus]
+ return gpu_names, gpu_count
+
+
+def get_driver_version():
+ """
+ Returns the driver version
+
+ In the case of multiple GPUs, will return the first.
+ """
+ output = subprocess.check_output(
+ [_nvidia_smi(), "--query-gpu=driver_version", "--format=csv,noheader"], universal_newlines=True
+ )
+ output = output.strip()
+ return output.split(os.linesep)[0]
+
+
+def check_cuda_p2p_ib_support():
+ """
+ Checks if the devices being used have issues with P2P and IB communications, namely any consumer GPU hardware after
+ the 3090.
+
+ Notably uses `nvidia-smi` instead of torch to not initialize CUDA.
+ """
+ try:
+ device_names, device_count = get_gpu_info()
+ # As new consumer GPUs get released, add them to `unsupported_devices``
+ unsupported_devices = {"RTX 40"}
+ if device_count > 1:
+ if any(
+ unsupported_device in device_name
+ for device_name in device_names
+ for unsupported_device in unsupported_devices
+ ):
+ # Check if they have the right driver version
+ acceptable_driver_version = "550.40.07"
+ current_driver_version = get_driver_version()
+ if parse(current_driver_version) < parse(acceptable_driver_version):
+ return False
+ return True
+ except Exception:
+ pass
+ return True
+
+
+@lru_cache
+def check_cuda_fp8_capability():
+ """
+ Checks if the current GPU available supports FP8.
+
+ Notably might initialize `torch.cuda` to check.
+ """
+
+ try:
+ # try to get the compute capability from nvidia-smi
+ output = subprocess.check_output(
+ [_nvidia_smi(), "--query-gpu=compute_capability", "--format=csv,noheader"], universal_newlines=True
+ )
+ output = output.strip()
+ # we take the first GPU's compute capability
+ compute_capability = tuple(map(int, output.split(os.linesep)[0].split(".")))
+ except Exception:
+ compute_capability = torch.cuda.get_device_capability()
+
+ return compute_capability >= (8, 9)
+
+
+@dataclass
+class CPUInformation:
+ """
+ Stores information about the CPU in a distributed environment. It contains the following attributes:
+ - rank: The rank of the current process.
+ - world_size: The total number of processes in the world.
+ - local_rank: The rank of the current process on the local node.
+ - local_world_size: The total number of processes on the local node.
+ """
+
+ rank: int = field(default=0, metadata={"help": "The rank of the current process."})
+ world_size: int = field(default=1, metadata={"help": "The total number of processes in the world."})
+ local_rank: int = field(default=0, metadata={"help": "The rank of the current process on the local node."})
+ local_world_size: int = field(default=1, metadata={"help": "The total number of processes on the local node."})
+
+
+def get_cpu_distributed_information() -> CPUInformation:
+ """
+ Returns various information about the environment in relation to CPU distributed training as a `CPUInformation`
+ dataclass.
+ """
+ information = {}
+ information["rank"] = get_int_from_env(["RANK", "PMI_RANK", "OMPI_COMM_WORLD_RANK", "MV2_COMM_WORLD_RANK"], 0)
+ information["world_size"] = get_int_from_env(
+ ["WORLD_SIZE", "PMI_SIZE", "OMPI_COMM_WORLD_SIZE", "MV2_COMM_WORLD_SIZE"], 1
+ )
+ information["local_rank"] = get_int_from_env(
+ ["LOCAL_RANK", "MPI_LOCALRANKID", "OMPI_COMM_WORLD_LOCAL_RANK", "MV2_COMM_WORLD_LOCAL_RANK"], 0
+ )
+ information["local_world_size"] = get_int_from_env(
+ ["LOCAL_WORLD_SIZE", "MPI_LOCALNRANKS", "OMPI_COMM_WORLD_LOCAL_SIZE", "MV2_COMM_WORLD_LOCAL_SIZE"],
+ 1,
+ )
+ return CPUInformation(**information)
+
+
+def override_numa_affinity(local_process_index: int, verbose: Optional[bool] = None) -> None:
+ """
+ Overrides whatever NUMA affinity is set for the current process. This is very taxing and requires recalculating the
+ affinity to set, ideally you should use `utils.environment.set_numa_affinity` instead.
+
+ Args:
+ local_process_index (int):
+ The index of the current process on the current server.
+ verbose (bool, *optional*):
+ Whether to log out the assignment of each CPU. If `ACCELERATE_DEBUG_MODE` is enabled, will default to True.
+ """
+ if verbose is None:
+ verbose = parse_flag_from_env("ACCELERATE_DEBUG_MODE", False)
+ if torch.cuda.is_available():
+ from accelerate.utils import is_pynvml_available
+
+ if not is_pynvml_available():
+ raise ImportError(
+ "To set CPU affinity on CUDA GPUs the `nvidia-ml-py` package must be available. (`pip install nvidia-ml-py`)"
+ )
+ import pynvml as nvml
+
+ # The below code is based on https://github.com/NVIDIA/DeepLearningExamples/blob/master/TensorFlow2/LanguageModeling/BERT/gpu_affinity.py
+ nvml.nvmlInit()
+ num_elements = math.ceil(os.cpu_count() / 64)
+ handle = nvml.nvmlDeviceGetHandleByIndex(local_process_index)
+ affinity_string = ""
+ for j in nvml.nvmlDeviceGetCpuAffinity(handle, num_elements):
+ # assume nvml returns list of 64 bit ints
+ affinity_string = f"{j:064b}{affinity_string}"
+ affinity_list = [int(x) for x in affinity_string]
+ affinity_list.reverse() # so core 0 is the 0th element
+ affinity_to_set = [i for i, e in enumerate(affinity_list) if e != 0]
+ os.sched_setaffinity(0, affinity_to_set)
+ if verbose:
+ cpu_cores = os.sched_getaffinity(0)
+ logger.info(f"Assigning {len(cpu_cores)} cpu cores to process {local_process_index}: {cpu_cores}")
+
+
+@lru_cache
+def set_numa_affinity(local_process_index: int, verbose: Optional[bool] = None) -> None:
+ """
+ Assigns the current process to a specific NUMA node. Ideally most efficient when having at least 2 cpus per node.
+
+ This result is cached between calls. If you want to override it, please use
+ `accelerate.utils.environment.override_numa_afifnity`.
+
+ Args:
+ local_process_index (int):
+ The index of the current process on the current server.
+ verbose (bool, *optional*):
+ Whether to print the new cpu cores assignment for each process. If `ACCELERATE_DEBUG_MODE` is enabled, will
+ default to True.
+ """
+ override_numa_affinity(local_process_index=local_process_index, verbose=verbose)
+
+
+@contextmanager
+def clear_environment():
+ """
+ A context manager that will temporarily clear environment variables.
+
+ When this context exits, the previous environment variables will be back.
+
+ Example:
+
+ ```python
+ >>> import os
+ >>> from accelerate.utils import clear_environment
+
+ >>> os.environ["FOO"] = "bar"
+ >>> with clear_environment():
+ ... print(os.environ)
+ ... os.environ["FOO"] = "new_bar"
+ ... print(os.environ["FOO"])
+ {}
+ new_bar
+
+ >>> print(os.environ["FOO"])
+ bar
+ ```
+ """
+ _old_os_environ = os.environ.copy()
+ os.environ.clear()
+
+ try:
+ yield
+ finally:
+ os.environ.clear() # clear any added keys,
+ os.environ.update(_old_os_environ) # then restore previous environment
+
+
+@contextmanager
+def patch_environment(**kwargs):
+ """
+ A context manager that will add each keyword argument passed to `os.environ` and remove them when exiting.
+
+ Will convert the values in `kwargs` to strings and upper-case all the keys.
+
+ Example:
+
+ ```python
+ >>> import os
+ >>> from accelerate.utils import patch_environment
+
+ >>> with patch_environment(FOO="bar"):
+ ... print(os.environ["FOO"]) # prints "bar"
+ >>> print(os.environ["FOO"]) # raises KeyError
+ ```
+ """
+ existing_vars = {}
+ for key, value in kwargs.items():
+ key = key.upper()
+ if key in os.environ:
+ existing_vars[key] = os.environ[key]
+ os.environ[key] = str(value)
+
+ try:
+ yield
+ finally:
+ for key in kwargs:
+ key = key.upper()
+ if key in existing_vars:
+ # restore previous value
+ os.environ[key] = existing_vars[key]
+ else:
+ os.environ.pop(key, None)
+
+
+def purge_accelerate_environment(func_or_cls):
+ """Decorator to clean up accelerate environment variables set by the decorated class or function.
+
+ In some circumstances, calling certain classes or functions can result in accelerate env vars being set and not
+ being cleaned up afterwards. As an example, when calling:
+
+ TrainingArguments(fp16=True, ...)
+
+ The following env var will be set:
+
+ ACCELERATE_MIXED_PRECISION=fp16
+
+ This can affect subsequent code, since the env var takes precedence over TrainingArguments(fp16=False). This is
+ especially relevant for unit testing, where we want to avoid the individual tests to have side effects on one
+ another. Decorate the unit test function or whole class with this decorator to ensure that after each test, the env
+ vars are cleaned up. This works for both unittest.TestCase and normal classes (pytest); it also works when
+ decorating the parent class.
+
+ """
+ prefix = "ACCELERATE_"
+
+ @contextmanager
+ def env_var_context():
+ # Store existing accelerate env vars
+ existing_vars = {k: v for k, v in os.environ.items() if k.startswith(prefix)}
+ try:
+ yield
+ finally:
+ # Restore original env vars or remove new ones
+ for key in [k for k in os.environ if k.startswith(prefix)]:
+ if key in existing_vars:
+ os.environ[key] = existing_vars[key]
+ else:
+ os.environ.pop(key, None)
+
+ def wrap_function(func):
+ @wraps(func)
+ def wrapper(*args, **kwargs):
+ with env_var_context():
+ return func(*args, **kwargs)
+
+ wrapper._accelerate_is_purged_environment_wrapped = True
+ return wrapper
+
+ if not isinstance(func_or_cls, type):
+ return wrap_function(func_or_cls)
+
+ # Handle classes by wrapping test methods
+ def wrap_test_methods(test_class_instance):
+ for name in dir(test_class_instance):
+ if name.startswith("test"):
+ method = getattr(test_class_instance, name)
+ if callable(method) and not hasattr(method, "_accelerate_is_purged_environment_wrapped"):
+ setattr(test_class_instance, name, wrap_function(method))
+ return test_class_instance
+
+ # Handle inheritance
+ wrap_test_methods(func_or_cls)
+ func_or_cls.__init_subclass__ = classmethod(lambda cls, **kw: wrap_test_methods(cls))
+ return func_or_cls
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/fsdp_utils.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/fsdp_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..b0475cb7d13fb5a6477a93455a9d025b6a582201
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/fsdp_utils.py
@@ -0,0 +1,829 @@
+# Copyright 2023 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import copy
+import functools
+import os
+import re
+import shutil
+import warnings
+from collections import defaultdict
+from collections.abc import Iterable
+from contextlib import nullcontext
+from pathlib import Path
+from typing import Callable, Union
+
+import torch
+
+from ..logging import get_logger
+from .constants import FSDP_MODEL_NAME, OPTIMIZER_NAME, SAFE_WEIGHTS_NAME, WEIGHTS_NAME
+from .dataclasses import get_module_class_from_name
+from .modeling import get_non_persistent_buffers, is_peft_model
+from .other import get_module_children_bottom_up, is_compiled_module, save
+from .versions import is_torch_version
+
+
+logger = get_logger(__name__)
+
+
+def enable_fsdp_ram_efficient_loading():
+ """
+ Enables RAM efficient loading of Hugging Face models for FSDP in the environment.
+ """
+ # Sets values for `transformers.modeling_utils.is_fsdp_enabled`
+ if "ACCELERATE_USE_FSDP" not in os.environ:
+ os.environ["ACCELERATE_USE_FSDP"] = "True"
+ os.environ["FSDP_CPU_RAM_EFFICIENT_LOADING"] = "True"
+
+
+def disable_fsdp_ram_efficient_loading():
+ """
+ Disables RAM efficient loading of Hugging Face models for FSDP in the environment.
+ """
+ os.environ["FSDP_CPU_RAM_EFFICIENT_LOADING"] = "False"
+
+
+def _get_model_state_dict(model, adapter_only=False, sd_options=None):
+ if adapter_only and is_peft_model(model):
+ from peft import get_peft_model_state_dict
+
+ return get_peft_model_state_dict(model, adapter_name=model.active_adapter)
+
+ # Invariant: `sd_options` is not None only for FSDP2
+ if sd_options is not None:
+ from torch.distributed.checkpoint.state_dict import get_model_state_dict
+
+ return get_model_state_dict(model, options=sd_options)
+ else:
+ return model.state_dict()
+
+
+def _set_model_state_dict(model, state_dict, adapter_only=False, sd_options=None):
+ if adapter_only and is_peft_model(model):
+ from peft import set_peft_model_state_dict
+
+ return set_peft_model_state_dict(model, state_dict, adapter_name=model.active_adapter)
+
+ # Invariant: `sd_options` is not None only for FSDP2
+ if sd_options is not None:
+ from torch.distributed.checkpoint.state_dict import set_model_state_dict
+
+ return set_model_state_dict(model, state_dict, options=sd_options)
+ else:
+ return model.load_state_dict(state_dict)
+
+
+def _prepare_sd_options(fsdp_plugin):
+ sd_options = None
+
+ # we use this only for FSDP2, as it requires torch >= 2.6.0 and this api requires torch >= 2.2.0
+ if fsdp_plugin.fsdp_version == 2:
+ from torch.distributed.checkpoint.state_dict import StateDictOptions
+ from torch.distributed.fsdp.fully_sharded_data_parallel import StateDictType
+
+ sd_options = StateDictOptions(
+ full_state_dict=fsdp_plugin.state_dict_type == StateDictType.FULL_STATE_DICT,
+ cpu_offload=getattr(fsdp_plugin.state_dict_config, "offload_to_cpu", False),
+ broadcast_from_rank0=getattr(fsdp_plugin.state_dict_config, "rank0_only", False),
+ )
+
+ return sd_options
+
+
+def save_fsdp_model(fsdp_plugin, accelerator, model, output_dir, model_index=0, adapter_only=False):
+ # Note: We import here to reduce import time from general modules, and isolate outside dependencies
+ import torch.distributed.checkpoint as dist_cp
+ from torch.distributed.checkpoint.default_planner import DefaultSavePlanner
+ from torch.distributed.fsdp.fully_sharded_data_parallel import FullyShardedDataParallel as FSDP
+ from torch.distributed.fsdp.fully_sharded_data_parallel import StateDictType
+
+ os.makedirs(output_dir, exist_ok=True)
+ if fsdp_plugin.state_dict_type == StateDictType.FULL_STATE_DICT:
+ # FSDP raises error when single GPU is used with `offload_to_cpu=True` for FULL_STATE_DICT
+ # so, only enable it when num_processes>1
+ is_multi_process = accelerator.num_processes > 1
+ fsdp_plugin.state_dict_config.offload_to_cpu = is_multi_process
+ fsdp_plugin.state_dict_config.rank0_only = is_multi_process
+
+ ctx = (
+ FSDP.state_dict_type(
+ model, fsdp_plugin.state_dict_type, fsdp_plugin.state_dict_config, fsdp_plugin.optim_state_dict_config
+ )
+ if fsdp_plugin.fsdp_version == 1
+ else nullcontext()
+ )
+ sd_options = _prepare_sd_options(fsdp_plugin)
+
+ with ctx:
+ state_dict = _get_model_state_dict(model, adapter_only=adapter_only, sd_options=sd_options)
+ if fsdp_plugin.state_dict_type == StateDictType.FULL_STATE_DICT:
+ weights_name = f"{FSDP_MODEL_NAME}.bin" if model_index == 0 else f"{FSDP_MODEL_NAME}_{model_index}.bin"
+ output_model_file = os.path.join(output_dir, weights_name)
+ if accelerator.process_index == 0:
+ logger.info(f"Saving model to {output_model_file}")
+ torch.save(state_dict, output_model_file)
+ logger.info(f"Model saved to {output_model_file}")
+ # Invariant: `LOCAL_STATE_DICT` is never possible with `FSDP2`
+ elif fsdp_plugin.state_dict_type == StateDictType.LOCAL_STATE_DICT:
+ weights_name = (
+ f"{FSDP_MODEL_NAME}_rank{accelerator.process_index}.bin"
+ if model_index == 0
+ else f"{FSDP_MODEL_NAME}_{model_index}_rank{accelerator.process_index}.bin"
+ )
+ output_model_file = os.path.join(output_dir, weights_name)
+ logger.info(f"Saving model to {output_model_file}")
+ torch.save(state_dict, output_model_file)
+ logger.info(f"Model saved to {output_model_file}")
+ elif fsdp_plugin.state_dict_type == StateDictType.SHARDED_STATE_DICT:
+ ckpt_dir = os.path.join(output_dir, f"{FSDP_MODEL_NAME}_{model_index}")
+ os.makedirs(ckpt_dir, exist_ok=True)
+ logger.info(f"Saving model to {ckpt_dir}")
+ state_dict = {"model": state_dict}
+
+ dist_cp.save(
+ state_dict=state_dict,
+ storage_writer=dist_cp.FileSystemWriter(ckpt_dir),
+ planner=DefaultSavePlanner(),
+ )
+ logger.info(f"Model saved to {ckpt_dir}")
+
+
+def load_fsdp_model(fsdp_plugin, accelerator, model, input_dir, model_index=0, adapter_only=False):
+ # Note: We import here to reduce import time from general modules, and isolate outside dependencies
+ import torch.distributed.checkpoint as dist_cp
+ from torch.distributed.checkpoint.default_planner import DefaultLoadPlanner
+ from torch.distributed.fsdp.fully_sharded_data_parallel import FullyShardedDataParallel as FSDP
+ from torch.distributed.fsdp.fully_sharded_data_parallel import StateDictType
+
+ accelerator.wait_for_everyone()
+ if fsdp_plugin.state_dict_type == StateDictType.FULL_STATE_DICT:
+ # FSDP raises error when single GPU is used with `offload_to_cpu=True` for FULL_STATE_DICT
+ # so, only enable it when num_processes>1
+ is_multi_process = accelerator.num_processes > 1
+ fsdp_plugin.state_dict_config.offload_to_cpu = is_multi_process
+ fsdp_plugin.state_dict_config.rank0_only = is_multi_process
+
+ ctx = (
+ FSDP.state_dict_type(
+ model, fsdp_plugin.state_dict_type, fsdp_plugin.state_dict_config, fsdp_plugin.optim_state_dict_config
+ )
+ if fsdp_plugin.fsdp_version == 1
+ else nullcontext()
+ )
+ sd_options = _prepare_sd_options(fsdp_plugin)
+ with ctx:
+ if fsdp_plugin.state_dict_type == StateDictType.FULL_STATE_DICT:
+ if type(model) is not FSDP and accelerator.process_index != 0 and not accelerator.is_fsdp2:
+ if not fsdp_plugin.sync_module_states and fsdp_plugin.fsdp_version == 1:
+ raise ValueError(
+ "Set the `sync_module_states` flag to `True` so that model states are synced across processes when "
+ "initializing FSDP object"
+ )
+ return
+ weights_name = f"{FSDP_MODEL_NAME}.bin" if model_index == 0 else f"{FSDP_MODEL_NAME}_{model_index}.bin"
+ input_model_file = os.path.join(input_dir, weights_name)
+ logger.info(f"Loading model from {input_model_file}")
+ # we want an empty state dict for FSDP2 as we use `broadcast_from_rank0`
+ load_model = not accelerator.is_fsdp2 or accelerator.is_main_process
+ if load_model:
+ state_dict = torch.load(input_model_file, weights_only=True)
+ else:
+ state_dict = {}
+ logger.info(f"Model loaded from {input_model_file}")
+ elif fsdp_plugin.state_dict_type == StateDictType.LOCAL_STATE_DICT:
+ weights_name = (
+ f"{FSDP_MODEL_NAME}_rank{accelerator.process_index}.bin"
+ if model_index == 0
+ else f"{FSDP_MODEL_NAME}_{model_index}_rank{accelerator.process_index}.bin"
+ )
+ input_model_file = os.path.join(input_dir, weights_name)
+ logger.info(f"Loading model from {input_model_file}")
+ state_dict = torch.load(input_model_file, weights_only=True)
+ logger.info(f"Model loaded from {input_model_file}")
+ elif fsdp_plugin.state_dict_type == StateDictType.SHARDED_STATE_DICT:
+ ckpt_dir = (
+ os.path.join(input_dir, f"{FSDP_MODEL_NAME}_{model_index}")
+ if f"{FSDP_MODEL_NAME}" not in input_dir
+ else input_dir
+ )
+ logger.info(f"Loading model from {ckpt_dir}")
+ state_dict = {"model": _get_model_state_dict(model, adapter_only=adapter_only, sd_options=sd_options)}
+ dist_cp.load(
+ state_dict=state_dict,
+ storage_reader=dist_cp.FileSystemReader(ckpt_dir),
+ planner=DefaultLoadPlanner(),
+ )
+ state_dict = state_dict["model"]
+ logger.info(f"Model loaded from {ckpt_dir}")
+
+ load_result = _set_model_state_dict(model, state_dict, adapter_only=adapter_only, sd_options=sd_options)
+ return load_result
+
+
+def save_fsdp_optimizer(fsdp_plugin, accelerator, optimizer, model, output_dir, optimizer_index=0):
+ # Note: We import here to reduce import time from general modules, and isolate outside dependencies
+ import torch.distributed.checkpoint as dist_cp
+ from torch.distributed.checkpoint.default_planner import DefaultSavePlanner
+ from torch.distributed.fsdp.fully_sharded_data_parallel import FullyShardedDataParallel as FSDP
+ from torch.distributed.fsdp.fully_sharded_data_parallel import StateDictType
+
+ os.makedirs(output_dir, exist_ok=True)
+
+ ctx = (
+ FSDP.state_dict_type(
+ model, fsdp_plugin.state_dict_type, fsdp_plugin.state_dict_config, fsdp_plugin.optim_state_dict_config
+ )
+ if fsdp_plugin.fsdp_version == 1
+ else nullcontext()
+ )
+
+ sd_options = _prepare_sd_options(fsdp_plugin)
+
+ with ctx:
+ if fsdp_plugin.fsdp_version == 2:
+ from torch.distributed.checkpoint.state_dict import get_optimizer_state_dict
+
+ optim_state = get_optimizer_state_dict(model, optimizer, options=sd_options)
+ else:
+ optim_state = FSDP.optim_state_dict(model, optimizer)
+
+ if fsdp_plugin.state_dict_type == StateDictType.FULL_STATE_DICT:
+ if accelerator.process_index == 0:
+ optim_state_name = (
+ f"{OPTIMIZER_NAME}.bin" if optimizer_index == 0 else f"{OPTIMIZER_NAME}_{optimizer_index}.bin"
+ )
+ output_optimizer_file = os.path.join(output_dir, optim_state_name)
+ logger.info(f"Saving Optimizer state to {output_optimizer_file}")
+ torch.save(optim_state, output_optimizer_file)
+ logger.info(f"Optimizer state saved in {output_optimizer_file}")
+ else:
+ ckpt_dir = os.path.join(output_dir, f"{OPTIMIZER_NAME}_{optimizer_index}")
+ os.makedirs(ckpt_dir, exist_ok=True)
+ logger.info(f"Saving Optimizer state to {ckpt_dir}")
+ dist_cp.save(
+ state_dict={"optimizer": optim_state},
+ storage_writer=dist_cp.FileSystemWriter(ckpt_dir),
+ planner=DefaultSavePlanner(),
+ )
+ logger.info(f"Optimizer state saved in {ckpt_dir}")
+
+
+def load_fsdp_optimizer(fsdp_plugin, accelerator, optimizer, model, input_dir, optimizer_index=0, adapter_only=False):
+ # Note: We import here to reduce import time from general modules, and isolate outside dependencies
+ import torch.distributed.checkpoint as dist_cp
+ from torch.distributed.fsdp.fully_sharded_data_parallel import FullyShardedDataParallel as FSDP
+ from torch.distributed.fsdp.fully_sharded_data_parallel import StateDictType
+
+ accelerator.wait_for_everyone()
+ ctx = (
+ FSDP.state_dict_type(
+ model, fsdp_plugin.state_dict_type, fsdp_plugin.state_dict_config, fsdp_plugin.optim_state_dict_config
+ )
+ if fsdp_plugin.fsdp_version == 1
+ else nullcontext()
+ )
+ sd_options = _prepare_sd_options(fsdp_plugin)
+ with ctx:
+ if fsdp_plugin.state_dict_type == StateDictType.FULL_STATE_DICT:
+ optim_state = None
+ if accelerator.process_index == 0 or not fsdp_plugin.optim_state_dict_config.rank0_only:
+ optimizer_name = (
+ f"{OPTIMIZER_NAME}.bin" if optimizer_index == 0 else f"{OPTIMIZER_NAME}_{optimizer_index}.bin"
+ )
+ input_optimizer_file = os.path.join(input_dir, optimizer_name)
+ logger.info(f"Loading Optimizer state from {input_optimizer_file}")
+ optim_state = torch.load(input_optimizer_file, weights_only=True)
+ logger.info(f"Optimizer state loaded from {input_optimizer_file}")
+ else:
+ ckpt_dir = (
+ os.path.join(input_dir, f"{OPTIMIZER_NAME}_{optimizer_index}")
+ if f"{OPTIMIZER_NAME}" not in input_dir
+ else input_dir
+ )
+ logger.info(f"Loading Optimizer from {ckpt_dir}")
+ optim_state = {"optimizer": optimizer.state_dict()}
+ dist_cp.load(
+ optim_state,
+ checkpoint_id=ckpt_dir,
+ storage_reader=dist_cp.FileSystemReader(ckpt_dir),
+ )
+ optim_state = optim_state["optimizer"]
+ logger.info(f"Optimizer loaded from {ckpt_dir}")
+
+ if fsdp_plugin.fsdp_version == 1:
+ flattened_osd = FSDP.optim_state_dict_to_load(model=model, optim=optimizer, optim_state_dict=optim_state)
+ optimizer.load_state_dict(flattened_osd)
+ else:
+ from torch.distributed.checkpoint.state_dict import set_optimizer_state_dict
+
+ set_optimizer_state_dict(model, optimizer, optim_state, options=sd_options)
+
+
+def _distributed_checkpoint_to_merged_weights(checkpoint_dir: str, save_path: str, safe_serialization: bool = True):
+ """
+ Passthrough to `torch.distributed.checkpoint.format_utils.dcp_to_torch_save`
+
+ Will save under `save_path` as either `model.safetensors` or `pytorch_model.bin`.
+ """
+ # Note: We import here to reduce import time from general modules, and isolate outside dependencies
+ import torch.distributed.checkpoint as dist_cp
+ import torch.distributed.checkpoint.format_utils as dist_cp_format_utils
+
+ state_dict = {}
+ save_path = Path(save_path)
+ save_path.mkdir(exist_ok=True)
+ dist_cp_format_utils._load_state_dict(
+ state_dict,
+ storage_reader=dist_cp.FileSystemReader(checkpoint_dir),
+ planner=dist_cp_format_utils._EmptyStateDictLoadPlanner(),
+ no_dist=True,
+ )
+ save_path = save_path / SAFE_WEIGHTS_NAME if safe_serialization else save_path / WEIGHTS_NAME
+
+ # To handle if state is a dict like {model: {...}}
+ if len(state_dict.keys()) == 1:
+ state_dict = state_dict[list(state_dict)[0]]
+ save(state_dict, save_path, safe_serialization=safe_serialization)
+ return save_path
+
+
+def merge_fsdp_weights(
+ checkpoint_dir: str, output_path: str, safe_serialization: bool = True, remove_checkpoint_dir: bool = False
+):
+ """
+ Merge the weights from sharded FSDP model checkpoints into a single combined checkpoint. Should be used if
+ `SHARDED_STATE_DICT` was used for the model. Weights will be saved to `{output_path}/model.safetensors` if
+ `safe_serialization` else `pytorch_model.bin`.
+
+ Note: this is a CPU-bound process.
+
+ Args:
+ checkpoint_dir (`str`):
+ The directory containing the FSDP checkpoints (can be either the model or optimizer).
+ output_path (`str`):
+ The path to save the merged checkpoint.
+ safe_serialization (`bool`, *optional*, defaults to `True`):
+ Whether to save the merged weights with safetensors (recommended).
+ remove_checkpoint_dir (`bool`, *optional*, defaults to `False`):
+ Whether to remove the checkpoint directory after merging.
+ """
+ checkpoint_dir = Path(checkpoint_dir)
+ from accelerate.state import PartialState
+
+ if not is_torch_version(">=", "2.3.0"):
+ raise ValueError("`merge_fsdp_weights` requires PyTorch >= 2.3.0`")
+
+ # Verify that the checkpoint directory exists
+ if not checkpoint_dir.exists():
+ model_path_exists = (checkpoint_dir / "pytorch_model_fsdp_0").exists()
+ optimizer_path_exists = (checkpoint_dir / "optimizer_0").exists()
+ err = f"Tried to load from {checkpoint_dir} but couldn't find a valid metadata file."
+ if model_path_exists and optimizer_path_exists:
+ err += " However, potential model and optimizer checkpoint directories exist."
+ err += f"Please pass in either {checkpoint_dir}/pytorch_model_fsdp_0 or {checkpoint_dir}/optimizer_0"
+ err += "instead."
+ elif model_path_exists:
+ err += " However, a potential model checkpoint directory exists."
+ err += f"Please try passing in {checkpoint_dir}/pytorch_model_fsdp_0 instead."
+ elif optimizer_path_exists:
+ err += " However, a potential optimizer checkpoint directory exists."
+ err += f"Please try passing in {checkpoint_dir}/optimizer_0 instead."
+ raise ValueError(err)
+
+ # To setup `save` to work
+ state = PartialState()
+ if state.is_main_process:
+ logger.info(f"Merging FSDP weights from {checkpoint_dir}")
+ save_path = _distributed_checkpoint_to_merged_weights(checkpoint_dir, output_path, safe_serialization)
+ logger.info(f"Successfully merged FSDP weights and saved to {save_path}")
+ if remove_checkpoint_dir:
+ logger.info(f"Removing old checkpoint directory {checkpoint_dir}")
+ shutil.rmtree(checkpoint_dir)
+ state.wait_for_everyone()
+
+
+def ensure_weights_retied(param_init_fn, model: torch.nn.Module, device: torch.device):
+ _tied_names = getattr(model, "_tied_weights_keys", None)
+ if not _tied_names:
+ # if no tied names just passthrough
+ return param_init_fn
+
+ # get map of parameter instances to params.
+ # - needed for replacement later
+ _tied_params = {}
+ for name in _tied_names:
+ name = name.split(".")
+ name, param_name = ".".join(name[:-1]), name[-1]
+ mod = model.get_submodule(name)
+ param = getattr(mod, param_name)
+
+ _tied_params[id(param)] = None # placeholder for the param first
+
+ # build param_init_fn for the case with tied params
+ def param_init_fn_tied_param(module: torch.nn.Module):
+ # track which params to tie
+ # - usually only 1, but for completeness consider > 1
+ params_to_tie = defaultdict(list)
+ for n, param in module.named_parameters(recurse=False):
+ if id(param) in _tied_params:
+ params_to_tie[id(param)].append(n)
+
+ # call the param init fn, which potentially re-allocates the
+ # parameters
+ module = param_init_fn(module)
+
+ # search the parameters again and tie them up again
+ for id_key, _param_names in params_to_tie.items():
+ for param_name in _param_names:
+ param = _tied_params[id_key]
+ if param is None:
+ # everything will be tied to the first time the
+ # param is observed
+ _tied_params[id_key] = getattr(module, param_name)
+ else:
+ setattr(module, param_name, param) # tie
+
+ return module
+
+ return param_init_fn_tied_param
+
+
+def fsdp2_load_full_state_dict(accelerator, model: torch.nn.Module, full_sd: dict):
+ """
+ Loads the full state dict (could be only on rank 0) into the sharded model. This is done by broadcasting the
+ parameters from rank 0 to all other ranks. This function modifies the model in-place.
+
+ Args:
+ accelerator (`Accelerator`): The accelerator instance
+ model (`torch.nn.Module`):
+ The model to load the state dict into, expected to be on meta device or a VRAM spike can occur
+ full_sd (`dict`): The full state dict to load, can only be on rank 0
+ """
+ import torch.distributed as dist
+ from torch.distributed.tensor import DTensor, distribute_tensor
+
+ # Model was previously copied to meta device
+ meta_sharded_sd = model.state_dict()
+ sharded_sd = {}
+
+ # Rank 0 distributes the full state dict to other ranks
+ def _infer_parameter_dtype(model, param_name, empty_param):
+ try:
+ old_param = model.get_parameter_or_buffer(param_name)
+ except AttributeError:
+ # Need this for LORA, as there some params are not *parameters* of sorts
+ base_param_name, local_param_name = param_name.rsplit(".", 1)
+ submodule = model.get_submodule(base_param_name)
+ old_param = getattr(submodule, local_param_name)
+
+ is_torch_e4m3fn_available = hasattr(torch, "float8_e4m3fn")
+ casting_dtype = None
+ is_param_float8_e4m3fn = is_torch_e4m3fn_available and empty_param.dtype == torch.float8_e4m3fn
+
+ if empty_param.dtype.is_floating_point and not is_param_float8_e4m3fn:
+ casting_dtype = old_param.dtype
+
+ return old_param is not None and old_param.is_contiguous(), casting_dtype
+
+ def _cast_and_contiguous(tensor, to_contiguous, dtype):
+ if dtype is not None:
+ tensor = tensor.to(dtype=dtype)
+ if to_contiguous:
+ tensor = tensor.contiguous()
+ return tensor
+
+ if accelerator.is_main_process:
+ for (param_name, full_param), sharded_param in zip(full_sd.items(), meta_sharded_sd.values()):
+ device_mesh = sharded_param.device_mesh
+ full_param = full_param.detach().to(device_mesh.device_type)
+ if isinstance(full_param, DTensor):
+ # dist.broadcast() only supports torch.Tensor.
+ # After prepare_tp(), model parameters may become DTensor.
+ # To broadcast such a parameter, convert it to a local tensor first.
+ full_param = full_param.to_local()
+ dist.broadcast(full_param, src=0, group=dist.group.WORLD)
+ sharded_tensor = distribute_tensor(full_param, device_mesh, sharded_param.placements)
+ to_contiguous, casting_dtype = _infer_parameter_dtype(
+ model,
+ param_name,
+ full_param,
+ )
+ sharded_tensor = _cast_and_contiguous(sharded_tensor, to_contiguous, casting_dtype)
+ sharded_sd[param_name] = sharded_tensor
+ # We need this else to have a matching `broadcast` for all of the ranks, else we deadlock
+ else:
+ for param_name, sharded_param in meta_sharded_sd.items():
+ device_mesh = sharded_param.device_mesh
+ full_tensor = torch.empty(sharded_param.size(), device=device_mesh.device_type, dtype=sharded_param.dtype)
+ dist.broadcast(full_tensor, src=0, group=dist.group.WORLD)
+ sharded_tensor = distribute_tensor(full_tensor, device_mesh, sharded_param.placements)
+ to_contiguous, casting_dtype = _infer_parameter_dtype(
+ model,
+ param_name,
+ full_tensor,
+ )
+ sharded_tensor = _cast_and_contiguous(sharded_tensor, to_contiguous, casting_dtype)
+ sharded_sd[param_name] = sharded_tensor
+
+ # we set `assign=True` because our params are on meta device
+ model.load_state_dict(sharded_sd, assign=True)
+ return model
+
+
+def fsdp2_switch_optimizer_parameters(optimizer: torch.optim.Optimizer, mapping: dict):
+ """
+ Switches the parameters of the optimizer to new ones (sharded parameters in usual case). This function modifies the
+ optimizer in-place.
+
+ Args:
+ optimizer (`torch.optim.Optimizer`): Optimizer instance which contains the original model parameters
+ mapping (`dict`): Mapping from the original parameter (specified by `data_ptr`) to the sharded parameter
+
+ Raises:
+ KeyError:
+ If a parameter in the optimizer couldn't be switched to its sharded version. This should never happen and
+ indicates a bug. If we kept the original params instead of raising, the training wouldn't be numerically
+ correct and weights wouldn't get updated.
+ """
+ from torch.distributed.tensor import DTensor
+
+ accessor_mapping = {}
+
+ accessor_mapping[DTensor] = "_local_tensor"
+ try:
+ for param_group in optimizer.param_groups:
+ param_group["params"] = [mapping[p.data_ptr] for p in param_group["params"]]
+ except KeyError:
+ # This shouldn't ever happen, but we want to fail here else training wouldn't be numerically correct
+ # This basically means that we're missing a mapping from the original parameter to the sharded parameter
+ raise KeyError(
+ "A parameter in the optimizer couldn't be switched to its sharded version. This breaks the training. Please raise an issue on GitHub."
+ )
+
+
+def fsdp2_apply_ac(accelerator, model: torch.nn.Module):
+ """
+ Applies the activation checkpointing to the model.
+
+ Args:
+ accelerator (`Accelerator`): The accelerator instance
+ model (`torch.nn.Module`): The model to apply the activation checkpointing to
+
+ Returns:
+ `torch.nn.Module`: The model with the activation checkpointing applied
+ """
+
+ from torch.distributed.algorithms._checkpoint.checkpoint_wrapper import (
+ checkpoint_wrapper,
+ )
+
+ auto_wrap_policy_func = fsdp2_prepare_auto_wrap_policy(accelerator.state.fsdp_plugin, model)
+
+ for layer_name, layer in get_module_children_bottom_up(model, return_fqns=True)[:-1]:
+ if len(layer_name.split(".")) > 1:
+ parent_name, child_name = layer_name.rsplit(".", 1)
+ else:
+ parent_name = None
+ child_name = layer_name
+
+ parent_module = model.get_submodule(parent_name) if parent_name else model
+ if auto_wrap_policy_func(parent_module):
+ layer = checkpoint_wrapper(layer, preserve_rng_state=False)
+ parent_module.register_module(child_name, layer)
+
+ return model
+
+
+def fsdp2_prepare_model(accelerator, model: torch.nn.Module) -> torch.nn.Module:
+ """Prepares the model for FSDP2 in-place. Also returns the model to avoid misuse of the original model.
+
+ Args:
+ accelerator (`Accelerator`): The accelerator instance
+ model (`torch.nn.Module`): The model to prepare
+
+ Returns:
+ `torch.nn.Module`: Prepared model
+ """
+ from torch.distributed.fsdp import FSDPModule, MixedPrecisionPolicy, fully_shard
+
+ is_type_fsdp = isinstance(model, FSDPModule) or (
+ is_compiled_module(model) and isinstance(model._orig_mod, FSDPModule)
+ )
+ if is_type_fsdp:
+ return model
+
+ fsdp2_plugin = accelerator.state.fsdp_plugin
+
+ fsdp2_plugin.set_auto_wrap_policy(model)
+
+ original_sd = model.state_dict()
+ mesh = getattr(accelerator, "torch_device_mesh", None)
+
+ fsdp2_kwargs = {
+ "reshard_after_forward": fsdp2_plugin.reshard_after_forward,
+ "offload_policy": fsdp2_plugin.cpu_offload,
+ # `fully_shard` doesn't accept `None` in case of `MixedPrecisionPolicy`
+ "mp_policy": fsdp2_plugin.mixed_precision_policy or MixedPrecisionPolicy(),
+ "mesh": mesh[tuple(accelerator.parallelism_config.fsdp_dim_names)] if mesh is not None else None,
+ "ignored_params": get_parameters_from_modules(fsdp2_plugin.ignored_modules, model, accelerator.device),
+ }
+
+ model_has_params4bit = False
+ for name, param in model.named_parameters():
+ # this is a temporary fix whereby loading models with bnb params cannot be moved from
+ # GPU to a meta device due with FSDP2 because torch operations don't return the original class type
+ # bypassing the move to meta will still cause the VRAM spike, but at least it still will load
+ if param.__class__.__name__ == "Params4bit":
+ model_has_params4bit = True
+ break
+
+ if fsdp2_plugin.cpu_ram_efficient_loading and not model_has_params4bit:
+ # Context: `fully_shard` moves the model to GPU if it was on CPU, however it can also be on `meta` and then it stays there even after `fully_shard`
+ # For this reason, we need to move the model to `meta` device, as then sharding happens on `meta` device
+ # If we kept the model on CPU (`cpu_ram_efficient_loading` has model be on CPU on all ranks, though non-main ranks only have `torch.empty`), `fully_shard` would move it to GPU
+ # Afterwards, when we call `fsdp2_load_full_state_dict`, us creating the state_dict would result into briefly having two copies of model state_dict on the GPU -> VRAM spike
+
+ # We need to keep the original non-persistent buffers, as those MAY not be in the state_dict, resulting in them staying on meta device
+ # Also, these buffers aren't getting sharded by default
+ # We get the FQNs of all non-persistent buffers, to re-register them after
+ non_persistent_buffer_fqns = get_non_persistent_buffers(model, recurse=True, fqns=True)
+ original_non_persistent_buffers = copy.deepcopy(
+ {k: v for k, v in model.named_buffers() if k in non_persistent_buffer_fqns}
+ )
+ # We move the model to meta device, as then sharding happens on meta device
+ model = model.to(torch.device("meta"))
+ # We need to re-tie the weights, not exactly sure why, but if we don't do this, reference to `lm_head/embed_tokens` stay hanging -> more VRAM usage
+ # We assume `transformers` models have a `tie_weights` method if they support it
+ if hasattr(model, "tie_weights"):
+ model.tie_weights()
+
+ auto_wrap_policy_func = fsdp2_prepare_auto_wrap_policy(fsdp2_plugin, model)
+ if auto_wrap_policy_func is not None:
+ # We skip the model itself, as that one is always wrapped
+ for module in get_module_children_bottom_up(model)[:-1]:
+ if auto_wrap_policy_func(module) and not isinstance(module, FSDPModule):
+ fully_shard(module, **fsdp2_kwargs)
+
+ if not isinstance(model, FSDPModule):
+ fully_shard(model, **fsdp2_kwargs)
+
+ if fsdp2_plugin.cpu_ram_efficient_loading:
+ # If `cpu_ram_efficient_loading` is enabled, only rank 0 loads the weights
+ # Other ranks have an empty model on `meta` device, so we need to distribute the weights properly
+ fsdp2_load_full_state_dict(accelerator, model, original_sd)
+
+ if fsdp2_plugin.cpu_ram_efficient_loading and not model_has_params4bit:
+ # We re-register the buffers, as they may not be in the state_dict
+ for fqn, buffer_tensor in original_non_persistent_buffers.items():
+ buffer_tensor = buffer_tensor.to(accelerator.device)
+
+ if "." in fqn:
+ parent_fqn, local_buffer_name = fqn.rsplit(".", 1)
+ parent_module = model.get_submodule(parent_fqn)
+ else:
+ local_buffer_name = fqn
+ parent_module = model
+
+ parent_module.register_buffer(local_buffer_name, buffer_tensor, persistent=False)
+
+ # We need to tie the weights again, as call to `load_full_state_dict` breaks the tie
+ # Needs to be called both here and above
+ # removing this call makes the have slightly different loss
+ # removing the call above leads to extra memory usage as explained in the comment above
+ if hasattr(model, "tie_weights"):
+ model.tie_weights()
+
+ # There is no `dtype` attribution for nn.Module
+ # Set it to None if it doesn't exist and do the upcast always
+ model_dtype = getattr(model, "dtype", None)
+ if accelerator.mixed_precision != "no" and (model_dtype is None or model_dtype != torch.float32):
+ # We upcast the model according to `deepspeed`'s implementation
+ # More info about this can be found in `accelerator.py:prepare_model`s FSDP1 section
+ model = model.to(torch.float32)
+ if accelerator.is_main_process:
+ # TODO(siro1): Add a warning for each parameter that was upcasted
+ warnings.warn(
+ "FSDP upcast of low precision parameters to fp32 (since mixed_precision != 'no') may affect the precision of model checkpoints."
+ )
+ return model
+
+
+def fsdp2_prepare_auto_wrap_policy(fsdp2_plugin, model: torch.nn.Module) -> Callable[[torch.nn.Module], bool]:
+ """Prepares the auto wrap policy based on its type, done to mimic the behaviour of FSDP1 auto wrap policy.
+
+ Args:
+ fsdp2_plugin (`FullyShardedDataParallelPlugin`):
+ Instance of `FullyShardedDataParallelPlugin` containing the configuration options
+ auto_wrap_policy_type (`str`):
+ Either `transformer` or `size`
+ model (`torch.nn.Module`):
+ The model to wrap
+
+ Returns:
+ `Callable[[torch.nn.Module], bool]`:
+ The auto wrap policy function to be applied to the model
+ """
+ from torch.distributed.fsdp.wrap import size_based_auto_wrap_policy, transformer_auto_wrap_policy
+
+ fn = fsdp2_plugin.auto_wrap_policy
+
+ if isinstance(fn, functools.partial):
+ fn = fn.func
+
+ if fn is transformer_auto_wrap_policy:
+ no_split_modules = getattr(model, "_no_split_modules", None)
+ if no_split_modules is None:
+ no_split_modules = []
+ transformer_cls_names_to_wrap = list(no_split_modules)
+ if fsdp2_plugin.transformer_cls_names_to_wrap is not None:
+ transformer_cls_names_to_wrap = fsdp2_plugin.transformer_cls_names_to_wrap
+ transformer_cls_to_wrap = set()
+
+ for layer_class in transformer_cls_names_to_wrap:
+ transformer_cls = get_module_class_from_name(model, layer_class)
+ if transformer_cls is None:
+ raise ValueError(f"Could not find the transformer layer class {layer_class} in the model.")
+ transformer_cls_to_wrap.add(transformer_cls)
+
+ def policy(module: torch.nn.Module) -> bool:
+ if fsdp2_plugin.transformer_cls_names_to_wrap is None:
+ return False
+ return isinstance(module, tuple(transformer_cls_to_wrap))
+
+ elif fn is size_based_auto_wrap_policy:
+
+ def policy(module: torch.nn.Module) -> bool:
+ module_num_params = sum(p.numel() for p in module.parameters())
+ return module_num_params > fsdp2_plugin.min_num_params
+ else:
+ return None
+
+ return policy
+
+
+def get_fsdp2_grad_scaler(**kwargs):
+ """
+ Returns a `GradScaler` for FSDP2, as the current implementation of `get_grad_scaler` doesn't accept other args. We
+ need this as current `get_grad_scaler` accepts only `distributed_type` as arg, which doesn't differentiate between
+ FSDP1 and FSDP2
+ """
+ from torch.amp.grad_scaler import GradScaler
+
+ return GradScaler(**kwargs)
+
+
+def fsdp2_canonicalize_names(named_params: dict) -> dict:
+ """Removes parameter name modifiers in order to map them back to their original names.
+
+ See huggingface/accelerate#3554 for more context.
+
+ Args:
+ named_params (`dict`): The named parameters dictionary to canonicalize.
+
+ Returns:
+ `dict`: The canonicalized named parameters dictionary
+ """
+ named_params = {k.replace("._checkpoint_wrapped_module", ""): v for k, v in named_params.items()}
+ named_params = {
+ k.replace("_orig_mod.", "") if k.startswith("_orig_mod.") else k: v for k, v in named_params.items()
+ }
+ named_params = {k.replace("._orig_mod", ""): v for k, v in named_params.items()}
+ return named_params
+
+
+def get_parameters_from_modules(
+ modules: Union[Iterable[torch.nn.Module], str], model, device
+) -> set[torch.nn.Parameter]:
+ """Converts modules to parameters where modules can be a string or list of torch.nn.Module
+
+ Args:
+ modules (`Union[Iterable[torch.nn.Module], str]`): List of modules
+
+ Returns:
+ `set[torch.nn.Parameter]`: List of parameters
+ """
+ if modules is None:
+ return set()
+ parameters = []
+ # code taken from accelerate while preparing kwargs for FSDP
+ if isinstance(modules, str):
+ reg = re.compile(modules)
+ mapped_modules = []
+ for name, module in model.named_modules():
+ if reg.fullmatch(name):
+ module.to(device)
+ mapped_modules.append(module)
+ modules = mapped_modules
+ for module in modules:
+ parameters.extend(list(module.parameters()))
+ return set(parameters)
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/imports.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/imports.py
new file mode 100644
index 0000000000000000000000000000000000000000..68cef6b4a4cafd65de5e82de155a316683cee737
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/imports.py
@@ -0,0 +1,564 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import importlib
+import importlib.metadata
+import os
+import sys
+import warnings
+from functools import lru_cache, wraps
+
+import torch
+from packaging import version
+from packaging.version import parse
+
+from .environment import parse_flag_from_env, patch_environment, str_to_bool
+from .versions import compare_versions, is_torch_version
+
+
+# Try to run Torch native job in an environment with TorchXLA installed by setting this value to 0.
+USE_TORCH_XLA = parse_flag_from_env("USE_TORCH_XLA", default=True)
+
+_torch_xla_available = False
+if USE_TORCH_XLA:
+ try:
+ import torch_xla.core.xla_model as xm # noqa: F401
+ import torch_xla.runtime
+
+ _torch_xla_available = True
+ except ImportError:
+ pass
+
+# Keep it for is_tpu_available. It will be removed along with is_tpu_available.
+_tpu_available = _torch_xla_available
+
+# Cache this result has it's a C FFI call which can be pretty time-consuming
+_torch_distributed_available = torch.distributed.is_available()
+
+
+def _is_package_available(pkg_name, metadata_name=None):
+ # Check we're not importing a "pkg_name" directory somewhere but the actual library by trying to grab the version
+ package_exists = importlib.util.find_spec(pkg_name) is not None
+ if package_exists:
+ try:
+ # Some libraries have different names in the metadata
+ _ = importlib.metadata.metadata(pkg_name if metadata_name is None else metadata_name)
+ return True
+ except importlib.metadata.PackageNotFoundError:
+ return False
+
+
+def is_torch_distributed_available() -> bool:
+ return _torch_distributed_available
+
+
+def is_xccl_available():
+ if is_torch_version(">=", "2.7.0"):
+ return torch.distributed.distributed_c10d.is_xccl_available()
+ if is_ipex_available():
+ return False
+ return False
+
+
+def is_ccl_available():
+ try:
+ pass
+ except ImportError:
+ print(
+ "Intel(R) oneCCL Bindings for PyTorch* is required to run DDP on Intel(R) XPUs, but it is not"
+ " detected. If you see \"ValueError: Invalid backend: 'ccl'\" error, please install Intel(R) oneCCL"
+ " Bindings for PyTorch*."
+ )
+ return importlib.util.find_spec("oneccl_bindings_for_pytorch") is not None
+
+
+def get_ccl_version():
+ return importlib.metadata.version("oneccl_bind_pt")
+
+
+def is_import_timer_available():
+ return _is_package_available("import_timer")
+
+
+def is_pynvml_available():
+ return _is_package_available("pynvml") or _is_package_available("pynvml", "nvidia-ml-py")
+
+
+def is_pytest_available():
+ return _is_package_available("pytest")
+
+
+def is_msamp_available():
+ return _is_package_available("msamp", "ms-amp")
+
+
+def is_schedulefree_available():
+ return _is_package_available("schedulefree")
+
+
+def is_transformer_engine_available():
+ if is_hpu_available():
+ return _is_package_available("intel_transformer_engine", "intel-transformer-engine")
+ else:
+ return _is_package_available("transformer_engine", "transformer-engine")
+
+
+def is_transformer_engine_mxfp8_available():
+ if _is_package_available("transformer_engine", "transformer-engine"):
+ import transformer_engine.pytorch as te
+
+ return te.fp8.check_mxfp8_support()[0]
+ return False
+
+
+def is_lomo_available():
+ return _is_package_available("lomo_optim")
+
+
+def is_cuda_available():
+ """
+ Checks if `cuda` is available via an `nvml-based` check which won't trigger the drivers and leave cuda
+ uninitialized.
+ """
+ with patch_environment(PYTORCH_NVML_BASED_CUDA_CHECK="1"):
+ available = torch.cuda.is_available()
+
+ return available
+
+
+@lru_cache
+def is_torch_xla_available(check_is_tpu=False, check_is_gpu=False):
+ """
+ Check if `torch_xla` is available. To train a native pytorch job in an environment with torch xla installed, set
+ the USE_TORCH_XLA to false.
+ """
+ assert not (check_is_tpu and check_is_gpu), "The check_is_tpu and check_is_gpu cannot both be true."
+
+ if not _torch_xla_available:
+ return False
+ elif check_is_gpu:
+ return torch_xla.runtime.device_type() in ["GPU", "CUDA"]
+ elif check_is_tpu:
+ return torch_xla.runtime.device_type() == "TPU"
+
+ return True
+
+
+def is_torchao_available():
+ package_exists = _is_package_available("torchao")
+ if package_exists:
+ torchao_version = version.parse(importlib.metadata.version("torchao"))
+ return compare_versions(torchao_version, ">=", "0.6.1")
+ return False
+
+
+def is_deepspeed_available():
+ return _is_package_available("deepspeed")
+
+
+def is_pippy_available():
+ return is_torch_version(">=", "2.4.0")
+
+
+def is_bf16_available(ignore_tpu=False):
+ "Checks if bf16 is supported, optionally ignoring the TPU"
+ if is_torch_xla_available(check_is_tpu=True):
+ return not ignore_tpu
+ if is_cuda_available():
+ return torch.cuda.is_bf16_supported()
+ if is_mlu_available():
+ return torch.mlu.is_bf16_supported()
+ if is_xpu_available():
+ return torch.xpu.is_bf16_supported()
+ if is_mps_available():
+ return torch.backends.mps.is_macos_or_newer(14, 0)
+ return True
+
+
+def is_fp16_available():
+ "Checks if fp16 is supported"
+ if is_habana_gaudi1():
+ return False
+
+ return True
+
+
+def is_fp8_available():
+ "Checks if fp8 is supported"
+ return is_msamp_available() or is_transformer_engine_available() or is_torchao_available()
+
+
+def is_4bit_bnb_available():
+ package_exists = _is_package_available("bitsandbytes")
+ if package_exists:
+ bnb_version = version.parse(importlib.metadata.version("bitsandbytes"))
+ return compare_versions(bnb_version, ">=", "0.39.0")
+ return False
+
+
+def is_8bit_bnb_available():
+ package_exists = _is_package_available("bitsandbytes")
+ if package_exists:
+ bnb_version = version.parse(importlib.metadata.version("bitsandbytes"))
+ return compare_versions(bnb_version, ">=", "0.37.2")
+ return False
+
+
+def is_bnb_available(min_version=None):
+ package_exists = _is_package_available("bitsandbytes")
+ if package_exists and min_version is not None:
+ bnb_version = version.parse(importlib.metadata.version("bitsandbytes"))
+ return compare_versions(bnb_version, ">=", min_version)
+ else:
+ return package_exists
+
+
+def is_bitsandbytes_multi_backend_available():
+ if not is_bnb_available():
+ return False
+ import bitsandbytes as bnb
+
+ return "multi_backend" in getattr(bnb, "features", set())
+
+
+def is_torchvision_available():
+ return _is_package_available("torchvision")
+
+
+def is_megatron_lm_available():
+ if str_to_bool(os.environ.get("ACCELERATE_USE_MEGATRON_LM", "False")) == 1:
+ if importlib.util.find_spec("megatron") is not None:
+ try:
+ megatron_version = parse(importlib.metadata.version("megatron-core"))
+ if compare_versions(megatron_version, ">=", "0.8.0"):
+ return importlib.util.find_spec(".training", "megatron")
+ except Exception as e:
+ warnings.warn(f"Parse Megatron version failed. Exception:{e}")
+ return False
+
+
+def is_transformers_available():
+ return _is_package_available("transformers")
+
+
+def is_datasets_available():
+ return _is_package_available("datasets")
+
+
+def is_peft_available():
+ return _is_package_available("peft")
+
+
+def is_timm_available():
+ return _is_package_available("timm")
+
+
+def is_triton_available():
+ if is_xpu_available():
+ return _is_package_available("triton", "pytorch-triton-xpu")
+ return _is_package_available("triton")
+
+
+def is_aim_available():
+ package_exists = _is_package_available("aim")
+ if package_exists:
+ aim_version = version.parse(importlib.metadata.version("aim"))
+ return compare_versions(aim_version, "<", "4.0.0")
+ return False
+
+
+def is_tensorboard_available():
+ return _is_package_available("tensorboard") or _is_package_available("tensorboardX")
+
+
+def is_wandb_available():
+ return _is_package_available("wandb")
+
+
+def is_comet_ml_available():
+ return _is_package_available("comet_ml")
+
+
+def is_swanlab_available():
+ return _is_package_available("swanlab")
+
+
+def is_trackio_available():
+ return sys.version_info >= (3, 10) and _is_package_available("trackio")
+
+
+def is_boto3_available():
+ return _is_package_available("boto3")
+
+
+def is_rich_available():
+ if _is_package_available("rich"):
+ return parse_flag_from_env("ACCELERATE_ENABLE_RICH", False)
+ return False
+
+
+def is_sagemaker_available():
+ return _is_package_available("sagemaker")
+
+
+def is_tqdm_available():
+ return _is_package_available("tqdm")
+
+
+def is_clearml_available():
+ return _is_package_available("clearml")
+
+
+def is_pandas_available():
+ return _is_package_available("pandas")
+
+
+def is_matplotlib_available():
+ return _is_package_available("matplotlib")
+
+
+def is_mlflow_available():
+ if _is_package_available("mlflow"):
+ return True
+
+ if importlib.util.find_spec("mlflow") is not None:
+ try:
+ _ = importlib.metadata.metadata("mlflow-skinny")
+ return True
+ except importlib.metadata.PackageNotFoundError:
+ return False
+ return False
+
+
+def is_mps_available(min_version="1.12"):
+ "Checks if MPS device is available. The minimum version required is 1.12."
+ # With torch 1.12, you can use torch.backends.mps
+ # With torch 2.0.0, you can use torch.mps
+ return is_torch_version(">=", min_version) and torch.backends.mps.is_available() and torch.backends.mps.is_built()
+
+
+def is_ipex_available():
+ "Checks if ipex is installed."
+
+ def get_major_and_minor_from_version(full_version):
+ return str(version.parse(full_version).major) + "." + str(version.parse(full_version).minor)
+
+ _torch_version = importlib.metadata.version("torch")
+ if importlib.util.find_spec("intel_extension_for_pytorch") is None:
+ return False
+ _ipex_version = "N/A"
+ try:
+ _ipex_version = importlib.metadata.version("intel_extension_for_pytorch")
+ except importlib.metadata.PackageNotFoundError:
+ return False
+ torch_major_and_minor = get_major_and_minor_from_version(_torch_version)
+ ipex_major_and_minor = get_major_and_minor_from_version(_ipex_version)
+ if torch_major_and_minor != ipex_major_and_minor:
+ warnings.warn(
+ f"Intel Extension for PyTorch {ipex_major_and_minor} needs to work with PyTorch {ipex_major_and_minor}.*,"
+ f" but PyTorch {_torch_version} is found. Please switch to the matching version and run again."
+ )
+ return False
+ return True
+
+
+@lru_cache
+def is_mlu_available(check_device=False):
+ """
+ Checks if `mlu` is available via an `cndev-based` check which won't trigger the drivers and leave mlu
+ uninitialized.
+ """
+ if importlib.util.find_spec("torch_mlu") is None:
+ return False
+
+ import torch_mlu # noqa: F401
+
+ with patch_environment(PYTORCH_CNDEV_BASED_MLU_CHECK="1"):
+ available = torch.mlu.is_available()
+
+ return available
+
+
+@lru_cache
+def is_musa_available(check_device=False):
+ "Checks if `torch_musa` is installed and potentially if a MUSA is in the environment"
+ if importlib.util.find_spec("torch_musa") is None:
+ return False
+
+ import torch_musa # noqa: F401
+
+ if check_device:
+ try:
+ # Will raise a RuntimeError if no MUSA is found
+ _ = torch.musa.device_count()
+ return torch.musa.is_available()
+ except RuntimeError:
+ return False
+ return hasattr(torch, "musa") and torch.musa.is_available()
+
+
+@lru_cache
+def is_npu_available(check_device=False):
+ "Checks if `torch_npu` is installed and potentially if a NPU is in the environment"
+ if importlib.util.find_spec("torch_npu") is None:
+ return False
+
+ # NOTE: importing torch_npu may raise error in some envs
+ # e.g. inside cpu-only container with torch_npu installed
+ try:
+ import torch_npu # noqa: F401
+ except Exception:
+ return False
+
+ if check_device:
+ try:
+ # Will raise a RuntimeError if no NPU is found
+ _ = torch.npu.device_count()
+ return torch.npu.is_available()
+ except RuntimeError:
+ return False
+ return hasattr(torch, "npu") and torch.npu.is_available()
+
+
+@lru_cache
+def is_sdaa_available(check_device=False):
+ "Checks if `torch_sdaa` is installed and potentially if a SDAA is in the environment"
+ if importlib.util.find_spec("torch_sdaa") is None:
+ return False
+
+ import torch_sdaa # noqa: F401
+
+ if check_device:
+ try:
+ # Will raise a RuntimeError if no NPU is found
+ _ = torch.sdaa.device_count()
+ return torch.sdaa.is_available()
+ except RuntimeError:
+ return False
+ return hasattr(torch, "sdaa") and torch.sdaa.is_available()
+
+
+@lru_cache
+def is_hpu_available(init_hccl=False):
+ "Checks if `torch.hpu` is installed and potentially if a HPU is in the environment"
+ if (
+ importlib.util.find_spec("habana_frameworks") is None
+ or importlib.util.find_spec("habana_frameworks.torch") is None
+ ):
+ return False
+
+ import habana_frameworks.torch # noqa: F401
+
+ if init_hccl:
+ import habana_frameworks.torch.distributed.hccl as hccl # noqa: F401
+
+ return hasattr(torch, "hpu") and torch.hpu.is_available()
+
+
+def is_habana_gaudi1():
+ if is_hpu_available():
+ import habana_frameworks.torch.utils.experimental as htexp # noqa: F401
+
+ if htexp._get_device_type() == htexp.synDeviceType.synDeviceGaudi:
+ return True
+
+ return False
+
+
+@lru_cache
+def is_xpu_available(check_device=False):
+ """
+ Checks if XPU acceleration is available either via `intel_extension_for_pytorch` or via stock PyTorch (>=2.4) and
+ potentially if a XPU is in the environment
+ """
+
+ if is_ipex_available():
+ import intel_extension_for_pytorch # noqa: F401
+ else:
+ if is_torch_version("<=", "2.3"):
+ return False
+
+ if check_device:
+ try:
+ # Will raise a RuntimeError if no XPU is found
+ _ = torch.xpu.device_count()
+ return torch.xpu.is_available()
+ except RuntimeError:
+ return False
+ return hasattr(torch, "xpu") and torch.xpu.is_available()
+
+
+def is_dvclive_available():
+ return _is_package_available("dvclive")
+
+
+def is_torchdata_available():
+ return _is_package_available("torchdata")
+
+
+# TODO: Remove this function once stateful_dataloader is a stable feature in torchdata.
+def is_torchdata_stateful_dataloader_available():
+ package_exists = _is_package_available("torchdata")
+ if package_exists:
+ torchdata_version = version.parse(importlib.metadata.version("torchdata"))
+ return compare_versions(torchdata_version, ">=", "0.8.0")
+ return False
+
+
+def torchao_required(func):
+ """
+ A decorator that ensures the decorated function is only called when torchao is available.
+ """
+
+ @wraps(func)
+ def wrapper(*args, **kwargs):
+ if not is_torchao_available():
+ raise ImportError(
+ "`torchao` is not available, please install it before calling this function via `pip install torchao`."
+ )
+ return func(*args, **kwargs)
+
+ return wrapper
+
+
+# TODO: Rework this into `utils.deepspeed` and migrate the "core" chunks into `accelerate.deepspeed`
+def deepspeed_required(func):
+ """
+ A decorator that ensures the decorated function is only called when deepspeed is enabled.
+ """
+
+ @wraps(func)
+ def wrapper(*args, **kwargs):
+ from accelerate.state import AcceleratorState
+ from accelerate.utils.dataclasses import DistributedType
+
+ if AcceleratorState._shared_state != {} and AcceleratorState().distributed_type != DistributedType.DEEPSPEED:
+ raise ValueError(
+ "DeepSpeed is not enabled, please make sure that an `Accelerator` is configured for `deepspeed` "
+ "before calling this function."
+ )
+ return func(*args, **kwargs)
+
+ return wrapper
+
+
+def is_weights_only_available():
+ # Weights only with allowlist was added in 2.4.0
+ # ref: https://github.com/pytorch/pytorch/pull/124331
+ return is_torch_version(">=", "2.4.0")
+
+
+def is_numpy_available(min_version="1.25.0"):
+ numpy_version = parse(importlib.metadata.version("numpy"))
+ return compare_versions(numpy_version, ">=", min_version)
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/launch.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/launch.py
new file mode 100644
index 0000000000000000000000000000000000000000..6182bd40d6f29086a0b01816569e147423c46192
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/launch.py
@@ -0,0 +1,781 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import argparse
+import os
+import subprocess
+import sys
+import warnings
+from ast import literal_eval
+from shutil import which
+from typing import Any
+
+import torch
+
+from ..commands.config.config_args import SageMakerConfig
+from ..utils import (
+ DynamoBackend,
+ PrecisionType,
+ is_ccl_available,
+ is_fp8_available,
+ is_hpu_available,
+ is_ipex_available,
+ is_mlu_available,
+ is_musa_available,
+ is_npu_available,
+ is_sdaa_available,
+ is_torch_xla_available,
+ is_xpu_available,
+)
+from ..utils.constants import DEEPSPEED_MULTINODE_LAUNCHERS
+from ..utils.other import get_free_port, is_port_in_use, merge_dicts
+from ..utils.versions import compare_versions
+from .dataclasses import DistributedType, SageMakerDistributedType
+
+
+def _filter_args(args, parser, default_args=[]):
+ """
+ Filters out all `accelerate` specific args
+ """
+ new_args, _ = parser.parse_known_args(default_args)
+ for key, value in vars(args).items():
+ if key in vars(new_args).keys():
+ setattr(new_args, key, value)
+ return new_args
+
+
+def _get_mpirun_args():
+ """
+ Determines the executable and argument names for mpirun, based on the type of install. The supported MPI programs
+ are: OpenMPI, Intel MPI, or MVAPICH.
+
+ Returns: Program name and arg names for hostfile, num processes, and processes per node
+ """
+ # Find the MPI program name
+ mpi_apps = [x for x in ["mpirun", "mpiexec"] if which(x)]
+
+ if len(mpi_apps) == 0:
+ raise OSError("mpirun or mpiexec were not found. Ensure that Intel MPI, Open MPI, or MVAPICH are installed.")
+
+ # Call the app with the --version flag to determine which MPI app is installed
+ mpi_app = mpi_apps[0]
+ mpirun_version = subprocess.check_output([mpi_app, "--version"])
+
+ if b"Open MPI" in mpirun_version:
+ return mpi_app, "--hostfile", "-n", "--npernode", "--bind-to"
+ else:
+ # Intel MPI and MVAPICH both use the same arg names
+ return mpi_app, "-f", "-n", "-ppn", ""
+
+
+def setup_fp8_env(args: argparse.Namespace, current_env: dict[str, str]):
+ """
+ Setup the FP8 environment variables.
+ """
+ prefix = "ACCELERATE_"
+ for arg in vars(args):
+ if arg.startswith("fp8_"):
+ value = getattr(args, arg)
+ if value is not None:
+ if arg == "fp8_override_linear_precision":
+ current_env[prefix + "FP8_OVERRIDE_FPROP"] = str(value[0])
+ current_env[prefix + "FP8_OVERRIDE_DGRAD"] = str(value[1])
+ current_env[prefix + "FP8_OVERRIDE_WGRAD"] = str(value[2])
+ else:
+ current_env[f"{prefix}{arg.upper()}"] = str(getattr(args, arg))
+ return current_env
+
+
+def prepare_simple_launcher_cmd_env(args: argparse.Namespace) -> tuple[list[str], dict[str, str]]:
+ """
+ Prepares and returns the command list and an environment with the correct simple launcher environment variables.
+ """
+ cmd = []
+ if args.no_python and args.module:
+ raise ValueError("--module and --no_python cannot be used together")
+
+ num_processes = getattr(args, "num_processes", None)
+ num_machines = args.num_machines
+ if args.mpirun_hostfile is not None:
+ mpi_app_name, hostfile_arg, num_proc_arg, proc_per_node_arg, bind_to_arg = _get_mpirun_args()
+ bind_to = getattr(args, "bind-to", "socket")
+ nproc_per_node = str(num_processes // num_machines) if num_processes and num_machines else "1"
+ cmd += [
+ mpi_app_name,
+ hostfile_arg,
+ args.mpirun_hostfile,
+ proc_per_node_arg,
+ nproc_per_node,
+ ]
+ if num_processes:
+ cmd += [num_proc_arg, str(num_processes)]
+ if bind_to_arg:
+ cmd += [bind_to_arg, bind_to]
+ if not args.no_python:
+ cmd.append(sys.executable)
+ if args.module:
+ cmd.append("-m")
+ cmd.append(args.training_script)
+ cmd.extend(args.training_script_args)
+
+ current_env = os.environ.copy()
+ current_env["ACCELERATE_USE_CPU"] = str(args.cpu or args.use_cpu)
+ if args.debug:
+ current_env["ACCELERATE_DEBUG_MODE"] = "true"
+ if args.gpu_ids != "all" and args.gpu_ids is not None:
+ if is_xpu_available():
+ current_env["ZE_AFFINITY_MASK"] = args.gpu_ids
+ elif is_mlu_available():
+ current_env["MLU_VISIBLE_DEVICES"] = args.gpu_ids
+ elif is_sdaa_available():
+ current_env["SDAA_VISIBLE_DEVICES"] = args.gpu_ids
+ elif is_musa_available():
+ current_env["MUSA_VISIBLE_DEVICES"] = args.gpu_ids
+ elif is_npu_available():
+ current_env["ASCEND_RT_VISIBLE_DEVICES"] = args.gpu_ids
+ elif is_hpu_available():
+ current_env["HABANA_VISIBLE_MODULES"] = args.gpu_ids
+ else:
+ current_env["CUDA_VISIBLE_DEVICES"] = args.gpu_ids
+ if num_machines > 1:
+ assert args.main_process_ip is not None, (
+ "When using multiple machines, you need to specify the main process IP."
+ )
+ assert args.main_process_port is not None, (
+ "When using multiple machines, you need to specify the main process port."
+ )
+
+ ccl_worker_count = getattr(args, "mpirun_ccl", 0) if is_ccl_available() else 0
+ if (num_processes is not None and num_processes > 1) or num_machines > 1:
+ current_env["MASTER_ADDR"] = args.main_process_ip if args.main_process_ip is not None else "127.0.0.1"
+ current_env["MASTER_PORT"] = str(args.main_process_port) if args.main_process_port is not None else "29500"
+ current_env["CCL_WORKER_COUNT"] = str(ccl_worker_count)
+ if current_env["ACCELERATE_USE_CPU"]:
+ current_env["KMP_AFFINITY"] = "granularity=fine,compact,1,0"
+ current_env["KMP_BLOCKTIME"] = str(1)
+
+ try:
+ mixed_precision = PrecisionType(args.mixed_precision.lower())
+ except ValueError:
+ raise ValueError(
+ f"Unknown mixed_precision mode: {args.mixed_precision.lower()}. Choose between {PrecisionType.list()}."
+ )
+
+ current_env["ACCELERATE_MIXED_PRECISION"] = str(mixed_precision)
+ if args.mixed_precision.lower() == "fp8":
+ if not is_fp8_available():
+ raise RuntimeError(
+ "FP8 is not available on this machine. Please ensure that either Transformer Engine, MSAMP or torchao is installed."
+ )
+ current_env = setup_fp8_env(args, current_env)
+
+ try:
+ dynamo_backend = DynamoBackend(args.dynamo_backend.upper())
+ except ValueError:
+ raise ValueError(
+ f"Unknown dynamo backend: {args.dynamo_backend.upper()}. Choose between {DynamoBackend.list()}."
+ )
+ current_env["ACCELERATE_DYNAMO_BACKEND"] = dynamo_backend.value
+ current_env["ACCELERATE_DYNAMO_MODE"] = args.dynamo_mode
+ current_env["ACCELERATE_DYNAMO_USE_FULLGRAPH"] = str(args.dynamo_use_fullgraph)
+ current_env["ACCELERATE_DYNAMO_USE_DYNAMIC"] = str(args.dynamo_use_dynamic)
+ current_env["ACCELERATE_DYNAMO_USE_REGIONAL_COMPILATION"] = str(args.dynamo_use_regional_compilation)
+
+ current_env["OMP_NUM_THREADS"] = str(args.num_cpu_threads_per_process)
+ if is_ipex_available():
+ current_env["ACCELERATE_USE_IPEX"] = str(args.ipex).lower()
+ if args.enable_cpu_affinity:
+ current_env["ACCELERATE_CPU_AFFINITY"] = "1"
+ return cmd, current_env
+
+
+def prepare_multi_gpu_env(args: argparse.Namespace) -> dict[str, str]:
+ """
+ Prepares and returns an environment with the correct multi-GPU environment variables.
+ """
+ # get free port and update configurations
+ if args.main_process_port == 0:
+ args.main_process_port = get_free_port()
+
+ elif args.main_process_port is None:
+ args.main_process_port = 29500
+
+ num_processes = args.num_processes
+ num_machines = args.num_machines
+ main_process_ip = args.main_process_ip
+ main_process_port = args.main_process_port
+ if num_machines > 1:
+ args.nproc_per_node = str(num_processes // num_machines)
+ args.nnodes = str(num_machines)
+ args.node_rank = int(args.machine_rank)
+ if getattr(args, "same_network", False):
+ args.master_addr = str(main_process_ip)
+ args.master_port = str(main_process_port)
+ else:
+ args.rdzv_endpoint = f"{main_process_ip}:{main_process_port}"
+ else:
+ args.nproc_per_node = str(num_processes)
+ if main_process_port is not None:
+ args.master_port = str(main_process_port)
+
+ # only need to check port availability in main process, in case we have to start multiple launchers on the same machine
+ # for some reasons like splitting log files.
+ need_port_check = num_machines <= 1 or int(args.machine_rank) == 0
+ if need_port_check and is_port_in_use(main_process_port):
+ if num_machines <= 1:
+ args.standalone = True
+ warnings.warn(
+ f"Port `{main_process_port}` is already in use. "
+ "Accelerate will attempt to launch in a standalone-like mode by finding an open port automatically for this session. "
+ "If this current attempt fails, or for more control in future runs, please specify a different port "
+ "(e.g., `--main_process_port `) or use `--main_process_port 0` for automatic selection "
+ "in your launch command or Accelerate config file."
+ )
+ else:
+ raise ConnectionError(
+ f"Tried to launch distributed communication on port `{main_process_port}`, but another process is utilizing it. "
+ "Please specify a different port (such as using the `--main_process_port` flag or specifying a different `main_process_port` in your config file)"
+ " and rerun your script. To automatically use the next open port (on a single node), you can set this to `0`."
+ )
+
+ if args.module and args.no_python:
+ raise ValueError("--module and --no_python cannot be used together")
+ elif args.module:
+ args.module = True
+ elif args.no_python:
+ args.no_python = True
+
+ current_env = os.environ.copy()
+ if args.debug:
+ current_env["ACCELERATE_DEBUG_MODE"] = "true"
+ gpu_ids = getattr(args, "gpu_ids", "all")
+ if gpu_ids != "all" and args.gpu_ids is not None:
+ if is_xpu_available():
+ current_env["ZE_AFFINITY_MASK"] = gpu_ids
+ elif is_mlu_available():
+ current_env["MLU_VISIBLE_DEVICES"] = gpu_ids
+ elif is_sdaa_available():
+ current_env["SDAA_VISIBLE_DEVICES"] = gpu_ids
+ elif is_musa_available():
+ current_env["MUSA_VISIBLE_DEVICES"] = gpu_ids
+ elif is_npu_available():
+ current_env["ASCEND_RT_VISIBLE_DEVICES"] = gpu_ids
+ elif is_hpu_available():
+ current_env["HABANA_VISIBLE_MODULES"] = gpu_ids
+ else:
+ current_env["CUDA_VISIBLE_DEVICES"] = gpu_ids
+ mixed_precision = args.mixed_precision.lower()
+ try:
+ mixed_precision = PrecisionType(mixed_precision)
+ except ValueError:
+ raise ValueError(f"Unknown mixed_precision mode: {mixed_precision}. Choose between {PrecisionType.list()}.")
+
+ current_env["ACCELERATE_MIXED_PRECISION"] = str(mixed_precision)
+ if args.mixed_precision.lower() == "fp8":
+ if not is_fp8_available():
+ raise RuntimeError(
+ "FP8 is not available on this machine. Please ensure that either Transformer Engine, MSAMP or torchao is installed."
+ )
+ current_env = setup_fp8_env(args, current_env)
+
+ try:
+ dynamo_backend = DynamoBackend(args.dynamo_backend.upper())
+ except ValueError:
+ raise ValueError(
+ f"Unknown dynamo backend: {args.dynamo_backend.upper()}. Choose between {DynamoBackend.list()}."
+ )
+ current_env["ACCELERATE_DYNAMO_BACKEND"] = dynamo_backend.value
+ current_env["ACCELERATE_DYNAMO_MODE"] = args.dynamo_mode
+ current_env["ACCELERATE_DYNAMO_USE_FULLGRAPH"] = str(args.dynamo_use_fullgraph)
+ current_env["ACCELERATE_DYNAMO_USE_DYNAMIC"] = str(args.dynamo_use_dynamic)
+ current_env["ACCELERATE_DYNAMO_USE_REGIONAL_COMPILATION"] = str(args.dynamo_use_regional_compilation)
+
+ if args.use_fsdp:
+ current_env["ACCELERATE_USE_FSDP"] = "true"
+ if args.fsdp_cpu_ram_efficient_loading and not args.fsdp_sync_module_states:
+ raise ValueError("When using `--fsdp_cpu_ram_efficient_loading` set `--fsdp_sync_module_states` to `True`")
+
+ current_env["FSDP_VERSION"] = str(args.fsdp_version) if hasattr(args, "fsdp_version") else "1"
+
+ # For backwards compatibility, we support this in launched scripts,
+ # however, we do not ask users for this in `accelerate config` CLI
+ current_env["FSDP_SHARDING_STRATEGY"] = str(args.fsdp_sharding_strategy)
+
+ current_env["FSDP_RESHARD_AFTER_FORWARD"] = str(args.fsdp_reshard_after_forward).lower()
+ current_env["FSDP_OFFLOAD_PARAMS"] = str(args.fsdp_offload_params).lower()
+ current_env["FSDP_MIN_NUM_PARAMS"] = str(args.fsdp_min_num_params)
+ if args.fsdp_auto_wrap_policy is not None:
+ current_env["FSDP_AUTO_WRAP_POLICY"] = str(args.fsdp_auto_wrap_policy)
+ if args.fsdp_transformer_layer_cls_to_wrap is not None:
+ current_env["FSDP_TRANSFORMER_CLS_TO_WRAP"] = str(args.fsdp_transformer_layer_cls_to_wrap)
+ if args.fsdp_backward_prefetch is not None:
+ current_env["FSDP_BACKWARD_PREFETCH"] = str(args.fsdp_backward_prefetch)
+ if args.fsdp_state_dict_type is not None:
+ current_env["FSDP_STATE_DICT_TYPE"] = str(args.fsdp_state_dict_type)
+ current_env["FSDP_FORWARD_PREFETCH"] = str(args.fsdp_forward_prefetch).lower()
+ current_env["FSDP_USE_ORIG_PARAMS"] = str(args.fsdp_use_orig_params).lower()
+ current_env["FSDP_CPU_RAM_EFFICIENT_LOADING"] = str(args.fsdp_cpu_ram_efficient_loading).lower()
+ current_env["FSDP_SYNC_MODULE_STATES"] = str(args.fsdp_sync_module_states).lower()
+ current_env["FSDP_ACTIVATION_CHECKPOINTING"] = str(args.fsdp_activation_checkpointing).lower()
+ if getattr(args, "fsdp_ignored_modules", None) is not None:
+ current_env["FSDP_IGNORED_MODULES"] = str(args.fsdp_ignored_modules)
+
+ if args.use_megatron_lm:
+ prefix = "MEGATRON_LM_"
+ current_env["ACCELERATE_USE_MEGATRON_LM"] = "true"
+ current_env[prefix + "TP_DEGREE"] = str(args.megatron_lm_tp_degree)
+ current_env[prefix + "PP_DEGREE"] = str(args.megatron_lm_pp_degree)
+ current_env[prefix + "GRADIENT_CLIPPING"] = str(args.megatron_lm_gradient_clipping)
+ if args.megatron_lm_num_micro_batches is not None:
+ current_env[prefix + "NUM_MICRO_BATCHES"] = str(args.megatron_lm_num_micro_batches)
+ if args.megatron_lm_sequence_parallelism is not None:
+ current_env[prefix + "SEQUENCE_PARALLELISM"] = str(args.megatron_lm_sequence_parallelism)
+ if args.megatron_lm_recompute_activations is not None:
+ current_env[prefix + "RECOMPUTE_ACTIVATIONS"] = str(args.megatron_lm_recompute_activations)
+ if args.megatron_lm_use_distributed_optimizer is not None:
+ current_env[prefix + "USE_DISTRIBUTED_OPTIMIZER"] = str(args.megatron_lm_use_distributed_optimizer)
+
+ current_env["OMP_NUM_THREADS"] = str(args.num_cpu_threads_per_process)
+ if args.enable_cpu_affinity:
+ current_env["ACCELERATE_CPU_AFFINITY"] = "1"
+
+ if args.use_parallelism_config:
+ current_env = prepare_extend_env_parallelism_config(args, current_env)
+
+ return current_env
+
+
+def prepare_extend_env_parallelism_config(
+ args: argparse.Namespace, current_env: dict
+) -> tuple[list[str], dict[str, str]]:
+ """
+ Extends `current_env` with context parallelism env vars if any have been set
+ """
+
+ prefix = "PARALLELISM_CONFIG_"
+
+ current_env["ACCELERATE_USE_PARALLELISM_CONFIG"] = "true"
+ current_env[prefix + "DP_REPLICATE_SIZE"] = str(args.parallelism_config_dp_replicate_size)
+ current_env[prefix + "DP_SHARD_SIZE"] = str(args.parallelism_config_dp_shard_size)
+ current_env[prefix + "TP_SIZE"] = str(args.parallelism_config_tp_size)
+ current_env[prefix + "CP_SIZE"] = str(args.parallelism_config_cp_size)
+ current_env[prefix + "CP_BACKEND"] = str(args.parallelism_config_cp_backend)
+ current_env[prefix + "SP_SIZE"] = str(args.parallelism_config_sp_size)
+ current_env[prefix + "SP_BACKEND"] = str(args.parallelism_config_sp_backend)
+ if args.parallelism_config_cp_size > 1:
+ current_env[prefix + "CP_COMM_STRATEGY"] = str(args.parallelism_config_cp_comm_strategy)
+ if args.parallelism_config_sp_size > 1:
+ current_env[prefix + "SP_SEQ_LENGTH"] = str(args.parallelism_config_sp_seq_length)
+ current_env[prefix + "SP_SEQ_LENGTH_IS_VARIABLE"] = str(args.parallelism_config_sp_seq_length_is_variable)
+ current_env[prefix + "SP_ATTN_IMPLEMENTATION"] = str(args.parallelism_config_sp_attn_implementation)
+
+ return current_env
+
+
+def prepare_deepspeed_cmd_env(args: argparse.Namespace) -> tuple[list[str], dict[str, str]]:
+ """
+ Prepares and returns the command list and an environment with the correct DeepSpeed environment variables.
+ """
+ # get free port and update configurations
+ if args.main_process_port == 0:
+ args.main_process_port = get_free_port()
+
+ elif args.main_process_port is None:
+ args.main_process_port = 29500
+
+ num_processes = args.num_processes
+ num_machines = args.num_machines
+ main_process_ip = args.main_process_ip
+ main_process_port = args.main_process_port
+ cmd = None
+
+ # make sure launcher is not None
+ if args.deepspeed_multinode_launcher is None:
+ # set to default pdsh
+ args.deepspeed_multinode_launcher = DEEPSPEED_MULTINODE_LAUNCHERS[0]
+
+ if num_machines > 1 and args.deepspeed_multinode_launcher != DEEPSPEED_MULTINODE_LAUNCHERS[1]:
+ cmd = ["deepspeed"]
+ cmd.extend(["--hostfile", str(args.deepspeed_hostfile)])
+ if args.deepspeed_multinode_launcher == "nossh":
+ if compare_versions("deepspeed", "<", "0.14.5"):
+ raise ValueError("nossh launcher requires DeepSpeed >= 0.14.5")
+ cmd.extend(["--node_rank", str(args.machine_rank), "--no_ssh"])
+ else:
+ cmd.extend(["--no_local_rank", "--launcher", str(args.deepspeed_multinode_launcher)])
+ if args.deepspeed_exclusion_filter is not None:
+ cmd.extend(
+ [
+ "--exclude",
+ str(args.deepspeed_exclusion_filter),
+ ]
+ )
+ elif args.deepspeed_inclusion_filter is not None:
+ cmd.extend(
+ [
+ "--include",
+ str(args.deepspeed_inclusion_filter),
+ ]
+ )
+ else:
+ cmd.extend(["--num_gpus", str(args.num_processes // args.num_machines)])
+ if main_process_ip:
+ cmd.extend(["--master_addr", str(main_process_ip)])
+ cmd.extend(["--master_port", str(main_process_port)])
+ if args.module and args.no_python:
+ raise ValueError("--module and --no_python cannot be used together")
+ elif args.module:
+ cmd.append("--module")
+ elif args.no_python:
+ cmd.append("--no_python")
+ cmd.append(args.training_script)
+ cmd.extend(args.training_script_args)
+ elif num_machines > 1 and args.deepspeed_multinode_launcher == DEEPSPEED_MULTINODE_LAUNCHERS[1]:
+ args.nproc_per_node = str(num_processes // num_machines)
+ args.nnodes = str(num_machines)
+ args.node_rank = int(args.machine_rank)
+ if getattr(args, "same_network", False):
+ args.master_addr = str(main_process_ip)
+ args.master_port = str(main_process_port)
+ else:
+ args.rdzv_endpoint = f"{main_process_ip}:{main_process_port}"
+ else:
+ args.nproc_per_node = str(num_processes)
+ if main_process_port is not None:
+ args.master_port = str(main_process_port)
+
+ # only need to check port availability in main process, in case we have to start multiple launchers on the same machine
+ # for some reasons like splitting log files.
+ need_port_check = num_machines <= 1 or int(args.machine_rank) == 0
+ if need_port_check and is_port_in_use(main_process_port):
+ if num_machines <= 1:
+ args.standalone = True
+ warnings.warn(
+ f"Port `{main_process_port}` is already in use. "
+ "Accelerate will attempt to launch in a standalone-like mode by finding an open port automatically for this session. "
+ "If this current attempt fails, or for more control in future runs, please specify a different port "
+ "(e.g., `--main_process_port `) or use `--main_process_port 0` for automatic selection "
+ "in your launch command or Accelerate config file."
+ )
+ else:
+ raise ConnectionError(
+ f"Tried to launch distributed communication on port `{main_process_port}`, but another process is utilizing it. "
+ "Please specify a different port (such as using the `--main_process_port` flag or specifying a different `main_process_port` in your config file)"
+ " and rerun your script. To automatically use the next open port (on a single node), you can set this to `0`."
+ )
+
+ if args.module and args.no_python:
+ raise ValueError("--module and --no_python cannot be used together")
+ elif args.module:
+ args.module = True
+ elif args.no_python:
+ args.no_python = True
+
+ current_env = os.environ.copy()
+ if args.debug:
+ current_env["ACCELERATE_DEBUG_MODE"] = "true"
+ gpu_ids = getattr(args, "gpu_ids", "all")
+ if gpu_ids != "all" and args.gpu_ids is not None:
+ if is_xpu_available():
+ current_env["ZE_AFFINITY_MASK"] = gpu_ids
+ elif is_mlu_available():
+ current_env["MLU_VISIBLE_DEVICES"] = gpu_ids
+ elif is_sdaa_available():
+ current_env["SDAA_VISIBLE_DEVICES"] = gpu_ids
+ elif is_musa_available():
+ current_env["MUSA_VISIBLE_DEVICES"] = gpu_ids
+ elif is_npu_available():
+ current_env["ASCEND_RT_VISIBLE_DEVICES"] = gpu_ids
+ elif is_hpu_available():
+ current_env["HABANA_VISIBLE_MODULES"] = gpu_ids
+ else:
+ current_env["CUDA_VISIBLE_DEVICES"] = gpu_ids
+ try:
+ mixed_precision = PrecisionType(args.mixed_precision.lower())
+ except ValueError:
+ raise ValueError(
+ f"Unknown mixed_precision mode: {args.mixed_precision.lower()}. Choose between {PrecisionType.list()}."
+ )
+
+ current_env["PYTHONPATH"] = env_var_path_add("PYTHONPATH", os.path.abspath("."))
+ current_env["ACCELERATE_MIXED_PRECISION"] = str(mixed_precision)
+ if args.mixed_precision.lower() == "fp8":
+ if not is_fp8_available():
+ raise RuntimeError(
+ "FP8 is not available on this machine. Please ensure that either Transformer Engine, MSAMP or torchao is installed."
+ )
+ current_env = setup_fp8_env(args, current_env)
+ current_env["ACCELERATE_CONFIG_DS_FIELDS"] = str(args.deepspeed_fields_from_accelerate_config).lower()
+ current_env["ACCELERATE_USE_DEEPSPEED"] = "true"
+ if args.zero_stage is not None:
+ current_env["ACCELERATE_DEEPSPEED_ZERO_STAGE"] = str(args.zero_stage)
+ if args.gradient_accumulation_steps is not None:
+ current_env["ACCELERATE_GRADIENT_ACCUMULATION_STEPS"] = str(args.gradient_accumulation_steps)
+ if args.gradient_clipping is not None:
+ current_env["ACCELERATE_GRADIENT_CLIPPING"] = str(args.gradient_clipping).lower()
+ if args.offload_optimizer_device is not None:
+ current_env["ACCELERATE_DEEPSPEED_OFFLOAD_OPTIMIZER_DEVICE"] = str(args.offload_optimizer_device).lower()
+ if args.offload_param_device is not None:
+ current_env["ACCELERATE_DEEPSPEED_OFFLOAD_PARAM_DEVICE"] = str(args.offload_param_device).lower()
+ if args.zero3_init_flag is not None:
+ current_env["ACCELERATE_DEEPSPEED_ZERO3_INIT"] = str(args.zero3_init_flag).lower()
+ if args.zero3_save_16bit_model is not None:
+ current_env["ACCELERATE_DEEPSPEED_ZERO3_SAVE_16BIT_MODEL"] = str(args.zero3_save_16bit_model).lower()
+ if args.deepspeed_config_file is not None:
+ current_env["ACCELERATE_DEEPSPEED_CONFIG_FILE"] = str(args.deepspeed_config_file)
+ if args.enable_cpu_affinity:
+ current_env["ACCELERATE_CPU_AFFINITY"] = "1"
+ if args.deepspeed_moe_layer_cls_names is not None:
+ current_env["ACCELERATE_DEEPSPEED_MOE_LAYER_CLS_NAMES"] = str(args.deepspeed_moe_layer_cls_names)
+
+ if args.use_parallelism_config:
+ current_env = prepare_extend_env_parallelism_config(args, current_env)
+
+ return cmd, current_env
+
+
+def prepare_tpu(
+ args: argparse.Namespace, current_env: dict[str, str], pod: bool = False
+) -> tuple[argparse.Namespace, dict[str, str]]:
+ """
+ Prepares and returns an environment with the correct TPU environment variables.
+ """
+ if args.mixed_precision == "bf16" and is_torch_xla_available(check_is_tpu=True):
+ if args.downcast_bf16:
+ current_env["XLA_DOWNCAST_BF16"] = "1"
+ else:
+ current_env["XLA_USE_BF16"] = "1"
+ if args.debug:
+ current_env["ACCELERATE_DEBUG_MODE"] = "true"
+ if pod:
+ # Take explicit args and set them up for XLA
+ args.vm = args.tpu_vm
+ args.tpu = args.tpu_name
+ return args, current_env
+
+
+def _convert_nargs_to_dict(nargs: list[str]) -> dict[str, str]:
+ if len(nargs) < 0:
+ return {}
+ # helper function to infer type for argsparser
+
+ def _infer_type(s):
+ try:
+ s = float(s)
+
+ if s // 1 == s:
+ return int(s)
+ return s
+ except ValueError:
+ return s
+
+ parser = argparse.ArgumentParser()
+ _, unknown = parser.parse_known_args(nargs)
+ for index, argument in enumerate(unknown):
+ if argument.startswith(("-", "--")):
+ action = None
+ if index + 1 < len(unknown): # checks if next index would be in list
+ if unknown[index + 1].startswith(("-", "--")): # checks if next element is an key
+ # raise an error if element is store_true or store_false
+ raise ValueError(
+ "SageMaker doesn’t support argparse actions for `store_true` or `store_false`. Please define explicit types"
+ )
+ else: # raise an error if last element is store_true or store_false
+ raise ValueError(
+ "SageMaker doesn’t support argparse actions for `store_true` or `store_false`. Please define explicit types"
+ )
+ # adds argument to parser based on action_store true
+ if action is None:
+ parser.add_argument(argument, type=_infer_type)
+ else:
+ parser.add_argument(argument, action=action)
+
+ return {
+ key: (literal_eval(value) if value in ("True", "False") else value)
+ for key, value in parser.parse_args(nargs).__dict__.items()
+ }
+
+
+def prepare_sagemager_args_inputs(
+ sagemaker_config: SageMakerConfig, args: argparse.Namespace
+) -> tuple[argparse.Namespace, dict[str, Any]]:
+ # configure environment
+ print("Configuring Amazon SageMaker environment")
+ os.environ["AWS_DEFAULT_REGION"] = sagemaker_config.region
+
+ # configure credentials
+ if sagemaker_config.profile is not None:
+ os.environ["AWS_PROFILE"] = sagemaker_config.profile
+ elif args.aws_access_key_id is not None and args.aws_secret_access_key is not None:
+ os.environ["AWS_ACCESS_KEY_ID"] = args.aws_access_key_id
+ os.environ["AWS_SECRET_ACCESS_KEY"] = args.aws_secret_access_key
+ else:
+ raise OSError("You need to provide an aws_access_key_id and aws_secret_access_key when not using aws_profile")
+
+ # extract needed arguments
+ source_dir = os.path.dirname(args.training_script)
+ if not source_dir: # checks if string is empty
+ source_dir = "."
+ entry_point = os.path.basename(args.training_script)
+ if not entry_point.endswith(".py"):
+ raise ValueError(f'Your training script should be a python script and not "{entry_point}"')
+
+ print("Converting Arguments to Hyperparameters")
+ hyperparameters = _convert_nargs_to_dict(args.training_script_args)
+
+ try:
+ mixed_precision = PrecisionType(args.mixed_precision.lower())
+ except ValueError:
+ raise ValueError(
+ f"Unknown mixed_precision mode: {args.mixed_precision.lower()}. Choose between {PrecisionType.list()}."
+ )
+
+ try:
+ dynamo_backend = DynamoBackend(args.dynamo_backend.upper())
+ except ValueError:
+ raise ValueError(
+ f"Unknown dynamo backend: {args.dynamo_backend.upper()}. Choose between {DynamoBackend.list()}."
+ )
+
+ # Environment variables to be set for use during training job
+ environment = {
+ "ACCELERATE_USE_SAGEMAKER": "true",
+ "ACCELERATE_MIXED_PRECISION": str(mixed_precision),
+ "ACCELERATE_DYNAMO_BACKEND": dynamo_backend.value,
+ "ACCELERATE_DYNAMO_MODE": args.dynamo_mode,
+ "ACCELERATE_DYNAMO_USE_FULLGRAPH": str(args.dynamo_use_fullgraph),
+ "ACCELERATE_DYNAMO_USE_DYNAMIC": str(args.dynamo_use_dynamic),
+ "ACCELERATE_DYNAMO_USE_REGIONAL_COMPILATION": str(args.dynamo_use_regional_compilation),
+ "ACCELERATE_SAGEMAKER_DISTRIBUTED_TYPE": sagemaker_config.distributed_type.value,
+ }
+ if args.mixed_precision.lower() == "fp8":
+ if not is_fp8_available():
+ raise RuntimeError(
+ "FP8 is not available on this machine. Please ensure that either Transformer Engine, MSAMP or torchao is installed."
+ )
+ environment = setup_fp8_env(args, environment)
+ # configure distribution set up
+ distribution = None
+ if sagemaker_config.distributed_type == SageMakerDistributedType.DATA_PARALLEL:
+ distribution = {"smdistributed": {"dataparallel": {"enabled": True}}}
+
+ # configure sagemaker inputs
+ sagemaker_inputs = None
+ if sagemaker_config.sagemaker_inputs_file is not None:
+ print(f"Loading SageMaker Inputs from {sagemaker_config.sagemaker_inputs_file} file")
+ sagemaker_inputs = {}
+ with open(sagemaker_config.sagemaker_inputs_file) as file:
+ for i, line in enumerate(file):
+ if i == 0:
+ continue
+ l = line.split("\t")
+ sagemaker_inputs[l[0]] = l[1].strip()
+ print(f"Loaded SageMaker Inputs: {sagemaker_inputs}")
+
+ # configure sagemaker metrics
+ sagemaker_metrics = None
+ if sagemaker_config.sagemaker_metrics_file is not None:
+ print(f"Loading SageMaker Metrics from {sagemaker_config.sagemaker_metrics_file} file")
+ sagemaker_metrics = []
+ with open(sagemaker_config.sagemaker_metrics_file) as file:
+ for i, line in enumerate(file):
+ if i == 0:
+ continue
+ l = line.split("\t")
+ metric_dict = {
+ "Name": l[0],
+ "Regex": l[1].strip(),
+ }
+ sagemaker_metrics.append(metric_dict)
+ print(f"Loaded SageMaker Metrics: {sagemaker_metrics}")
+
+ # configure session
+ print("Creating Estimator")
+ args = {
+ "image_uri": sagemaker_config.image_uri,
+ "entry_point": entry_point,
+ "source_dir": source_dir,
+ "role": sagemaker_config.iam_role_name,
+ "transformers_version": sagemaker_config.transformers_version,
+ "pytorch_version": sagemaker_config.pytorch_version,
+ "py_version": sagemaker_config.py_version,
+ "base_job_name": sagemaker_config.base_job_name,
+ "instance_count": sagemaker_config.num_machines,
+ "instance_type": sagemaker_config.ec2_instance_type,
+ "debugger_hook_config": False,
+ "distribution": distribution,
+ "hyperparameters": hyperparameters,
+ "environment": environment,
+ "metric_definitions": sagemaker_metrics,
+ }
+
+ if sagemaker_config.additional_args is not None:
+ args = merge_dicts(sagemaker_config.additional_args, args)
+ return args, sagemaker_inputs
+
+
+def env_var_path_add(env_var_name, path_to_add):
+ """
+ Extends a path-based environment variable's value with a new path and returns the updated value. It's up to the
+ caller to set it in os.environ.
+ """
+ paths = [p for p in os.environ.get(env_var_name, "").split(":") if len(p) > 0]
+ paths.append(str(path_to_add))
+ return ":".join(paths)
+
+
+class PrepareForLaunch:
+ """
+ Prepare a function that will launched in a distributed setup.
+
+ Args:
+ launcher (`Callable`):
+ The function to launch.
+ distributed_type ([`~state.DistributedType`]):
+ The distributed type to prepare for.
+ debug (`bool`, *optional*, defaults to `False`):
+ Whether or not this is a debug launch.
+ """
+
+ def __init__(self, launcher, distributed_type="NO", debug=False):
+ self.launcher = launcher
+ self.distributed_type = DistributedType(distributed_type)
+ self.debug = debug
+
+ def __call__(self, index, *args):
+ if self.debug:
+ world_size = int(os.environ.get("WORLD_SIZE"))
+ rdv_file = os.environ.get("ACCELERATE_DEBUG_RDV_FILE")
+ torch.distributed.init_process_group(
+ "gloo",
+ rank=index,
+ store=torch.distributed.FileStore(rdv_file, world_size),
+ world_size=world_size,
+ )
+ elif self.distributed_type in (
+ DistributedType.MULTI_GPU,
+ DistributedType.MULTI_MLU,
+ DistributedType.MULTI_MUSA,
+ DistributedType.MULTI_NPU,
+ DistributedType.MULTI_XPU,
+ DistributedType.MULTI_CPU,
+ ):
+ # Prepare the environment for torch.distributed
+ os.environ["LOCAL_RANK"] = str(index)
+ nproc = int(os.environ.get("NPROC", 1))
+ node_rank = int(os.environ.get("NODE_RANK", 0))
+ os.environ["RANK"] = str(nproc * node_rank + index)
+
+ os.environ["FORK_LAUNCHED"] = str(1)
+ self.launcher(*args)
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/megatron_lm.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/megatron_lm.py
new file mode 100644
index 0000000000000000000000000000000000000000..e3754098801102d67b98cebae5bf18b2fd6129d2
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/megatron_lm.py
@@ -0,0 +1,1424 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import argparse
+import math
+import os
+from abc import ABC
+from functools import partial
+
+import torch
+import torch.nn.functional as F
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+from torch.nn.parallel.distributed import DistributedDataParallel as torchDDP
+
+from ..optimizer import AcceleratedOptimizer
+from ..scheduler import AcceleratedScheduler
+from .imports import is_megatron_lm_available
+from .operations import recursively_apply, send_to_device
+
+
+if is_megatron_lm_available():
+ from megatron.core import mpu, tensor_parallel
+ from megatron.core.distributed import DistributedDataParallel as LocalDDP
+ from megatron.core.distributed import finalize_model_grads
+ from megatron.core.enums import ModelType
+ from megatron.core.num_microbatches_calculator import get_num_microbatches
+ from megatron.core.optimizer import get_megatron_optimizer
+ from megatron.core.parallel_state import get_tensor_model_parallel_group, get_tensor_model_parallel_src_rank
+ from megatron.core.pipeline_parallel import get_forward_backward_func
+ from megatron.core.utils import get_model_config
+ from megatron.inference.text_generation.communication import broadcast_int_list, broadcast_tensor
+ from megatron.inference.text_generation.generation import (
+ beam_search_and_return_on_first_stage,
+ generate_tokens_probs_and_return_on_first_stage,
+ )
+ from megatron.legacy.data.dataset_utils import build_train_valid_test_datasets
+ from megatron.legacy.model import BertModel, Float16Module, GPTModel, T5Model
+ from megatron.legacy.model.classification import Classification
+ from megatron.training import (
+ get_args,
+ get_tensorboard_writer,
+ get_tokenizer,
+ print_rank_last,
+ )
+ from megatron.training.arguments import (
+ _add_data_args,
+ _add_validation_args,
+ core_transformer_config_from_args,
+ parse_args,
+ validate_args,
+ )
+ from megatron.training.checkpointing import load_args_from_checkpoint, load_checkpoint, save_checkpoint
+ from megatron.training.global_vars import set_global_variables
+ from megatron.training.initialize import (
+ _compile_dependencies,
+ _init_autoresume,
+ _initialize_distributed,
+ _set_random_seed,
+ set_jit_fusion_options,
+ write_args_to_tensorboard,
+ )
+ from megatron.training.tokenizer.tokenizer import _vocab_size_with_padding
+ from megatron.training.training import (
+ build_train_valid_test_data_iterators,
+ get_optimizer_param_scheduler,
+ num_floating_point_operations,
+ setup_model_and_optimizer,
+ train_step,
+ training_log,
+ )
+ from megatron.training.utils import (
+ average_losses_across_data_parallel_group,
+ calc_params_l2_norm,
+ get_ltor_masks_and_position_ids,
+ unwrap_model,
+ )
+
+
+# model utilities
+def model_provider_func(pre_process=True, post_process=True, add_encoder=True, add_decoder=True):
+ """Build the model."""
+ args = get_args()
+ mode = "pre-training" if args.pretraining_flag else "fine-tuning"
+ if args.rank == 0:
+ print(f"Building {args.model_type_name} model in the {mode} mode.")
+ print(
+ "The Megatron LM model weights are initialized at random in `accelerator.prepare`. "
+ "Please use `accelerator.load_checkpoint` to load a pre-trained checkpoint matching the distributed setup."
+ )
+ config = core_transformer_config_from_args(args)
+ if args.model_type_name == "bert":
+ if args.pretraining_flag:
+ num_tokentypes = 2 if args.bert_binary_head else 0
+ model = BertModel(
+ config=config,
+ num_tokentypes=num_tokentypes,
+ add_binary_head=args.bert_binary_head,
+ parallel_output=True,
+ pre_process=pre_process,
+ post_process=post_process,
+ )
+ else:
+ model = Classification(
+ config=config,
+ num_classes=args.num_labels,
+ num_tokentypes=2,
+ pre_process=pre_process,
+ post_process=post_process,
+ )
+ elif args.model_type_name == "gpt":
+ model = GPTModel(
+ config=config,
+ num_tokentypes=0,
+ parallel_output=True,
+ pre_process=pre_process,
+ post_process=post_process,
+ )
+ elif args.model_type_name == "t5":
+ model = T5Model(
+ config=config,
+ num_tokentypes=0,
+ parallel_output=True,
+ pre_process=pre_process,
+ post_process=post_process,
+ add_encoder=add_encoder,
+ add_decoder=add_decoder,
+ )
+ else:
+ raise ValueError(f"Unsupported model type: {args.model_type_name}")
+ return model
+
+
+def prepare_model_optimizer_scheduler(accelerator):
+ accelerator.print("Preparing model optimizer scheduler")
+ args = get_args()
+ if accelerator.state.megatron_lm_plugin.custom_prepare_model_function is not None:
+ if accelerator.state.megatron_lm_plugin.custom_model_provider_function is None:
+ raise ValueError(
+ "You must provide a `custom_model_provider_function` when using a `custom_prepare_model_function`."
+ )
+ custom_model_provider_func = accelerator.state.megatron_lm_plugin.custom_model_provider_function
+ model = accelerator.state.megatron_lm_plugin.custom_prepare_model_function(custom_model_provider_func)
+ optimizer = prepare_optimizer(accelerator, model)
+ scheduler = prepare_scheduler(accelerator, optimizer, scheduler=None)
+ else:
+ model_type = ModelType.encoder_or_decoder
+ if args.model_type_name == "t5":
+ model_type = ModelType.encoder_and_decoder
+ model_provider_func_ = model_provider_func
+ if accelerator.state.megatron_lm_plugin.custom_model_provider_function is not None:
+ model_provider_func_ = accelerator.state.megatron_lm_plugin.custom_model_provider_function
+ (model, optimizer, scheduler) = setup_model_and_optimizer(
+ model_provider_func_,
+ model_type,
+ no_wd_decay_cond=args.no_wd_decay_cond,
+ scale_lr_cond=args.scale_lr_cond,
+ lr_mult=args.lr_mult,
+ )
+ args.model_len = len(model)
+ return model, optimizer, scheduler
+
+
+# dataloader utilities
+class MegatronLMDummyDataLoader:
+ """
+ Dummy dataloader presents model parameters or param groups, this is primarily used to follow conventional training
+
+ Args:
+ **dataset_kwargs: Megatron data arguments.
+ """
+
+ def __init__(self, **dataset_kwargs):
+ parser = argparse.ArgumentParser()
+ parser = _add_data_args(parser)
+ parser = _add_validation_args(parser)
+ data_args = parser.parse_known_args()
+ self.dataset_args = vars(data_args[0])
+ self.dataset_args.update(dataset_kwargs)
+ self.dataset_args["megatron_dataset_flag"] = True
+
+ def set_megatron_data_args(self):
+ args = get_args()
+ for key, value in self.dataset_args.items():
+ old_value = getattr(args, key, "")
+ if old_value != value:
+ print(
+ f"WARNING: MegatronLMDummyDataLoader overriding arguments for {key}:{old_value} with {key}:{value}"
+ )
+ setattr(args, key, value)
+
+ def get_train_valid_test_datasets_provider(self, accelerator):
+ def train_valid_test_datasets_provider(train_val_test_num_samples):
+ """Build train, valid, and test datasets."""
+ args = get_args()
+ dataset_args = {
+ "data_prefix": args.data_path if isinstance(args.data_path, (list, tuple)) else [args.data_path],
+ "splits_string": args.split,
+ "train_valid_test_num_samples": train_val_test_num_samples,
+ "seed": args.seed,
+ }
+ if args.model_type_name == "bert":
+ dataset_args.update(
+ {
+ "max_seq_length": args.seq_length,
+ "binary_head": args.bert_binary_head,
+ }
+ )
+ elif args.model_type_name == "gpt":
+ dataset_args.update(
+ {
+ "max_seq_length": args.seq_length,
+ }
+ )
+ elif args.model_type_name == "t5":
+ dataset_args.update(
+ {
+ "max_seq_length": args.encoder_seq_length,
+ "max_seq_length_dec": args.decoder_seq_length,
+ "dataset_type": "t5",
+ }
+ )
+ else:
+ raise ValueError(f"Unsupported model type: {args.model_type_name}")
+ train_ds, valid_ds, test_ds = build_train_valid_test_datasets(**dataset_args)
+ return train_ds, valid_ds, test_ds
+
+ if accelerator.state.megatron_lm_plugin.custom_megatron_datasets_provider_function is not None:
+ return accelerator.state.megatron_lm_plugin.custom_megatron_datasets_provider_function
+ try:
+ args = get_args()
+ # Use '--no-use-pep517 -e' to pip install nvidia's megatron from source
+ if args.model_type_name == "bert":
+ from pretrain_bert import train_valid_test_datasets_provider
+
+ train_valid_test_datasets_provider.is_distributed = True
+ return train_valid_test_datasets_provider
+ elif args.model_type_name == "gpt":
+ from pretrain_gpt import train_valid_test_datasets_provider
+
+ train_valid_test_datasets_provider.is_distributed = True
+ return train_valid_test_datasets_provider
+ elif args.model_type_name == "t5":
+ from pretrain_t5 import train_valid_test_datasets_provider
+
+ train_valid_test_datasets_provider.is_distributed = True
+ return train_valid_test_datasets_provider
+ except ImportError:
+ pass
+ return train_valid_test_datasets_provider
+
+ def build_train_valid_test_data_iterators(self, accelerator):
+ args = get_args()
+
+ train_valid_test_dataset_provider = self.get_train_valid_test_datasets_provider(accelerator)
+ if args.virtual_pipeline_model_parallel_size is not None:
+ train_data_iterator = []
+ valid_data_iterator = []
+ test_data_iterator = []
+ for i in range(getattr(args, "model_len", 0)):
+ mpu.set_virtual_pipeline_model_parallel_rank(i)
+ iterators = build_train_valid_test_data_iterators(train_valid_test_dataset_provider)
+ train_data_iterator.append(iterators[0])
+ valid_data_iterator.append(iterators[1])
+ test_data_iterator.append(iterators[2])
+ else:
+ train_data_iterator, valid_data_iterator, test_data_iterator = build_train_valid_test_data_iterators(
+ train_valid_test_dataset_provider
+ )
+
+ return train_data_iterator, valid_data_iterator, test_data_iterator
+
+
+def _handle_megatron_data_iterator(accelerator, data_iterator):
+ class DummyMegatronDataloader:
+ def __iter__(self):
+ return self
+
+ def __next__(self):
+ return {}
+
+ is_data_iterator_empty = data_iterator is None
+ is_src_data_iterator_empty = torch.tensor(is_data_iterator_empty, dtype=torch.bool, device=accelerator.device)
+ torch.distributed.broadcast(
+ is_src_data_iterator_empty, get_tensor_model_parallel_src_rank(), group=get_tensor_model_parallel_group()
+ )
+ if not is_src_data_iterator_empty and is_data_iterator_empty:
+ return DummyMegatronDataloader()
+ return data_iterator
+
+
+def prepare_data_loader(accelerator, dataloader):
+ accelerator.print("Preparing dataloader")
+ args = get_args()
+ if not args.megatron_dataset_flag:
+ from ..data_loader import _PYTORCH_DATALOADER_KWARGS, prepare_data_loader
+
+ micro_batch_size = args.micro_batch_size * args.num_micro_batches
+ kwargs = {k: getattr(dataloader, k, _PYTORCH_DATALOADER_KWARGS[k]) for k in _PYTORCH_DATALOADER_KWARGS}
+ if kwargs["batch_size"] is None:
+ if isinstance(kwargs["sampler"], torch.utils.data.BatchSampler):
+ kwargs["sampler"].batch_size = micro_batch_size
+ else:
+ del kwargs["sampler"]
+ del kwargs["shuffle"]
+ del kwargs["batch_size"]
+ kwargs["batch_sampler"].batch_size = micro_batch_size
+ else:
+ del kwargs["batch_sampler"]
+ kwargs["batch_size"] = micro_batch_size
+
+ dataloader = torch.utils.data.DataLoader(dataloader.dataset, **kwargs)
+ # split_batches:
+ # Megatron only needs to fetch different data between different dp groups,
+ # and does not need to split the data within the dp group.
+ return prepare_data_loader(
+ dataloader,
+ accelerator.device,
+ num_processes=mpu.get_data_parallel_world_size(),
+ process_index=mpu.get_data_parallel_rank(),
+ split_batches=False,
+ put_on_device=True,
+ rng_types=accelerator.rng_types.copy(),
+ dispatch_batches=accelerator.dispatch_batches,
+ )
+ else:
+ if args.consumed_samples is not None:
+ (
+ args.consumed_train_samples,
+ args.consumed_valid_samples,
+ args.consumed_test_samples,
+ ) = args.consumed_samples
+ else:
+ args.consumed_train_samples, args.consumed_valid_samples, args.consumed_test_samples = 0, 0, 0
+ args.micro_batch_size = args.micro_batch_size * args.num_micro_batches
+ # In order to be compatible with data in transform format,
+ # it needs to increase the size of mbs first,
+ # and then split the large batch data into some mbs.
+ (
+ train_data_iterator,
+ valid_data_iterator,
+ test_data_iterator,
+ ) = dataloader.build_train_valid_test_data_iterators(accelerator)
+ args.micro_batch_size = args.micro_batch_size // args.num_micro_batches
+
+ train_data_iterator = _handle_megatron_data_iterator(
+ accelerator=accelerator, data_iterator=train_data_iterator
+ )
+ valid_data_iterator = _handle_megatron_data_iterator(
+ accelerator=accelerator, data_iterator=valid_data_iterator
+ )
+ test_data_iterator = _handle_megatron_data_iterator(accelerator=accelerator, data_iterator=test_data_iterator)
+
+ return train_data_iterator, valid_data_iterator, test_data_iterator
+
+
+# optimizer utilities
+class MegatronLMOptimizerWrapper(AcceleratedOptimizer):
+ def __init__(self, optimizer):
+ super().__init__(optimizer, device_placement=False, scaler=None)
+
+ def zero_grad(self, set_to_none=None):
+ pass # `model(**batch)` is doing that automatically. Therefore, its implementation is not needed
+
+ def step(self):
+ pass # `model(**batch)` is doing that automatically. Therefore, its implementation is not needed
+
+ @property
+ def step_was_skipped(self):
+ """Whether or not the optimizer step was done, or skipped because of gradient overflow."""
+ return self.optimizer.skipped_iter
+
+
+def prepare_optimizer(accelerator, model):
+ accelerator.print("Preparing optimizer")
+ args = get_args()
+ return get_megatron_optimizer(model, args.no_wd_decay_cond, args.scale_lr_cond, args.lr_mult)
+
+
+# scheduler utilities
+class MegatronLMDummyScheduler:
+ """
+ Dummy scheduler presents model parameters or param groups, this is primarily used to follow conventional training
+ loop when scheduler config is specified in the deepspeed config file.
+
+ Args:
+ optimizer (`torch.optim.optimizer.Optimizer`):
+ The optimizer to wrap.
+ total_num_steps (int):
+ Total number of steps.
+ warmup_num_steps (int):
+ Number of steps for warmup.
+ **kwargs (additional keyword arguments, *optional*):
+ Other arguments.
+ """
+
+ def __init__(self, optimizer, total_num_steps=None, warmup_num_steps=0, **kwargs):
+ self.optimizer = optimizer
+ self.total_num_steps = total_num_steps
+ self.warmup_num_steps = warmup_num_steps
+ self.kwargs = kwargs
+
+
+class MegatronLMSchedulerWrapper(AcceleratedScheduler):
+ def __init__(self, scheduler, optimizers):
+ super().__init__(scheduler, optimizers)
+
+ def step(self, *args, **kwargs):
+ return # `model(**batch)` is doing that automatically. Therefore, its implementation is not needed
+
+
+def prepare_scheduler(accelerator, optimizer, scheduler):
+ accelerator.print("Preparing scheduler")
+ scheduler = get_optimizer_param_scheduler(optimizer)
+ return scheduler
+
+
+class AbstractTrainStep(ABC):
+ """Abstract class for batching, forward pass and loss handler."""
+
+ def __init__(self, name):
+ super().__init__()
+ self.name = name
+
+ def get_batch_func(self, accelerator, megatron_dataset_flag):
+ pass
+
+ def get_forward_step_func(self):
+ pass
+
+ def get_loss_func(self, accelerator):
+ pass
+
+
+class BertTrainStep(AbstractTrainStep):
+ """
+ Bert train step class.
+
+ Args:
+ args (`argparse.Namespace`): Megatron-LM arguments.
+ """
+
+ def __init__(self, accelerator, args):
+ super().__init__("BertTrainStep")
+ self.get_batch = self.get_batch_func(accelerator, args.megatron_dataset_flag)
+ self.loss_func = self.get_loss_func(accelerator, args.pretraining_flag, args.num_labels)
+ self.forward_step = self.get_forward_step_func(args.pretraining_flag, args.bert_binary_head)
+ if not args.model_return_dict:
+ self.model_output_class = None
+ else:
+ from transformers.modeling_outputs import SequenceClassifierOutput
+
+ self.model_output_class = SequenceClassifierOutput
+
+ def get_batch_func(self, accelerator, megatron_dataset_flag):
+ def get_batch_megatron(data_iterator):
+ """Build the batch."""
+
+ # Items and their type.
+ keys = ["text", "types", "labels", "is_random", "loss_mask", "padding_mask"]
+ datatype = torch.int64
+
+ # Broadcast data.
+ if data_iterator is not None:
+ data = next(data_iterator)
+ else:
+ data = None
+ data_b = tensor_parallel.broadcast_data(keys, data, datatype)
+
+ # Unpack.
+ tokens = data_b["text"].long()
+ types = data_b["types"].long()
+ sentence_order = data_b["is_random"].long()
+ loss_mask = data_b["loss_mask"].float()
+ lm_labels = data_b["labels"].long()
+ padding_mask = data_b["padding_mask"].long()
+
+ return tokens, types, sentence_order, loss_mask, lm_labels, padding_mask
+
+ def get_batch_transformer(data_iterator):
+ """Build the batch."""
+ data = next(data_iterator)
+ data = send_to_device(data, torch.cuda.current_device())
+
+ # Unpack.
+ tokens = data["input_ids"].long()
+ padding_mask = data["attention_mask"].long()
+ if "token_type_ids" in data:
+ types = data["token_type_ids"].long()
+ else:
+ types = None
+ if "labels" in data:
+ lm_labels = data["labels"].long()
+ loss_mask = (data["labels"] != -100).to(torch.float)
+ else:
+ lm_labels = None
+ loss_mask = None
+ if "next_sentence_label" in data:
+ sentence_order = data["next_sentence_label"].long()
+ else:
+ sentence_order = None
+
+ return tokens, types, sentence_order, loss_mask, lm_labels, padding_mask
+
+ if accelerator.state.megatron_lm_plugin.custom_get_batch_function is not None:
+ return accelerator.state.megatron_lm_plugin.custom_get_batch_function
+ if megatron_dataset_flag:
+ try:
+ # Use '--no-use-pep517 -e' to pip install nvidia's megatron from source
+ from pretrain_bert import get_batch
+
+ return get_batch
+ except ImportError:
+ pass
+ return get_batch_megatron
+ else:
+ return get_batch_transformer
+
+ def get_loss_func(self, accelerator, pretraining_flag, num_labels):
+ def loss_func_pretrain(loss_mask, sentence_order, output_tensor):
+ lm_loss_, sop_logits = output_tensor
+
+ lm_loss_ = lm_loss_.float()
+ loss_mask = loss_mask.float()
+ lm_loss = torch.sum(lm_loss_.view(-1) * loss_mask.reshape(-1)) / loss_mask.sum()
+
+ if sop_logits is not None:
+ sop_loss = F.cross_entropy(sop_logits.view(-1, 2).float(), sentence_order.view(-1), ignore_index=-1)
+ sop_loss = sop_loss.float()
+ loss = lm_loss + sop_loss
+ averaged_losses = average_losses_across_data_parallel_group([lm_loss, sop_loss])
+ return loss, {"lm loss": averaged_losses[0], "sop loss": averaged_losses[1]}
+
+ else:
+ loss = lm_loss
+ averaged_losses = average_losses_across_data_parallel_group([lm_loss])
+ return loss, {"lm loss": averaged_losses[0]}
+
+ def loss_func_finetune(labels, logits):
+ if num_labels == 1:
+ # We are doing regression
+ loss_fct = MSELoss()
+ loss = loss_fct(logits.view(-1), labels.view(-1))
+ elif self.num_labels > 1 and (labels.dtype in (torch.long, torch.int)):
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, num_labels), labels.view(-1))
+ else:
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+ averaged_losses = average_losses_across_data_parallel_group([loss])
+ return loss, {"loss": averaged_losses[0]}
+
+ if accelerator.state.megatron_lm_plugin.custom_loss_function is not None:
+ return accelerator.state.megatron_lm_plugin.custom_loss_function
+ if pretraining_flag:
+ return loss_func_pretrain
+ else:
+ return loss_func_finetune
+
+ def get_forward_step_func(self, pretraining_flag, bert_binary_head):
+ def forward_step(data_iterator, model):
+ """Forward step."""
+ tokens, types, sentence_order, loss_mask, labels, padding_mask = self.get_batch(data_iterator)
+ if not bert_binary_head:
+ types = None
+ # Forward pass through the model.
+ if pretraining_flag:
+ output_tensor = model(tokens, padding_mask, tokentype_ids=types, lm_labels=labels)
+ return output_tensor, partial(self.loss_func, loss_mask, sentence_order)
+ else:
+ logits = model(tokens, padding_mask, tokentype_ids=types)
+ return logits, partial(self.loss_func, labels)
+
+ return forward_step
+
+
+class GPTTrainStep(AbstractTrainStep):
+ """
+ GPT train step class.
+
+ Args:
+ args (`argparse.Namespace`): Megatron-LM arguments.
+ """
+
+ def __init__(self, accelerator, args):
+ super().__init__("GPTTrainStep")
+ self.get_batch = self.get_batch_func(accelerator, args.megatron_dataset_flag)
+ self.loss_func = self.get_loss_func(accelerator)
+ self.forward_step = self.get_forward_step_func()
+ self.eod_token = args.padded_vocab_size - 1
+ if args.vocab_file is not None:
+ tokenizer = get_tokenizer()
+ self.eod_token = tokenizer.eod
+ self.reset_position_ids = args.reset_position_ids
+ self.reset_attention_mask = args.reset_attention_mask
+ self.eod_mask_loss = args.eod_mask_loss
+ if not args.model_return_dict:
+ self.model_output_class = None
+ else:
+ from transformers.modeling_outputs import CausalLMOutputWithCrossAttentions
+
+ self.model_output_class = CausalLMOutputWithCrossAttentions
+
+ def get_batch_func(self, accelerator, megatron_dataset_flag):
+ def get_batch_megatron(data_iterator):
+ """Generate a batch"""
+ # Items and their type.
+ keys = ["text"]
+ datatype = torch.int64
+
+ # Broadcast data.
+ if data_iterator is not None:
+ data = next(data_iterator)
+ else:
+ data = None
+ data_b = tensor_parallel.broadcast_data(keys, data, datatype)
+
+ # Unpack.
+ tokens_ = data_b["text"].long()
+ labels = tokens_[:, 1:].contiguous()
+ tokens = tokens_[:, :-1].contiguous()
+
+ # Get the masks and position ids.
+ attention_mask, loss_mask, position_ids = get_ltor_masks_and_position_ids(
+ tokens, self.eod_token, self.reset_position_ids, self.reset_attention_mask, self.eod_mask_loss
+ )
+
+ return tokens, labels, loss_mask, attention_mask, position_ids
+
+ def get_batch_transformer(data_iterator):
+ data = next(data_iterator)
+ data = {"input_ids": data["input_ids"]}
+ data = send_to_device(data, torch.cuda.current_device())
+
+ tokens_ = data["input_ids"].long()
+ padding = torch.zeros((tokens_.shape[0], 1), dtype=tokens_.dtype, device=tokens_.device) + self.eod_token
+ tokens_ = torch.concat([tokens_, padding], dim=1)
+ labels = tokens_[:, 1:].contiguous()
+ tokens = tokens_[:, :-1].contiguous()
+ # Get the masks and position ids.
+ attention_mask, loss_mask, position_ids = get_ltor_masks_and_position_ids(
+ tokens, self.eod_token, self.reset_position_ids, self.reset_attention_mask, True
+ )
+ return tokens, labels, loss_mask, attention_mask, position_ids
+
+ if accelerator.state.megatron_lm_plugin.custom_get_batch_function is not None:
+ return accelerator.state.megatron_lm_plugin.custom_get_batch_function
+ if megatron_dataset_flag:
+ try:
+ # Use '--no-use-pep517 -e' to pip install nvidia's megatron from source
+ from pretrain_gpt import get_batch
+
+ return get_batch
+ except ImportError:
+ pass
+ return get_batch_megatron
+ else:
+ return get_batch_transformer
+
+ def get_loss_func(self, accelerator):
+ args = get_args()
+
+ def loss_func(loss_mask, output_tensor):
+ if args.return_logits:
+ losses, logits = output_tensor
+ else:
+ losses = output_tensor
+ losses = losses.float()
+ loss_mask = loss_mask.view(-1).float()
+ if args.context_parallel_size > 1:
+ loss = torch.cat([torch.sum(losses.view(-1) * loss_mask).view(1), loss_mask.sum().view(1)])
+ torch.distributed.all_reduce(loss, group=mpu.get_context_parallel_group())
+ loss = loss[0] / loss[1]
+ else:
+ loss = torch.sum(losses.view(-1) * loss_mask) / loss_mask.sum()
+
+ # Check individual rank losses are not NaN prior to DP all-reduce.
+ if args.check_for_nan_in_loss_and_grad:
+ global_rank = torch.distributed.get_rank()
+ assert not loss.isnan(), (
+ f"Rank {global_rank}: found NaN in local forward loss calculation. "
+ f"Device: {torch.cuda.current_device()}, node: {os.uname()[1]}"
+ )
+
+ # Reduce loss for logging.
+ averaged_loss = average_losses_across_data_parallel_group([loss])
+
+ output_dict = {"lm loss": averaged_loss[0]}
+ if args.return_logits:
+ output_dict.update({"logits": logits})
+ return loss, output_dict
+
+ if accelerator.state.megatron_lm_plugin.custom_loss_function is not None:
+ return accelerator.state.megatron_lm_plugin.custom_loss_function
+ return loss_func
+
+ def get_forward_step_func(self):
+ def forward_step(data_iterator, model):
+ """Forward step."""
+ # Get the batch.
+ tokens, labels, loss_mask, attention_mask, position_ids = self.get_batch(data_iterator)
+ output_tensor = model(tokens, position_ids, attention_mask, labels=labels)
+
+ return output_tensor, partial(self.loss_func, loss_mask)
+
+ return forward_step
+
+
+class T5TrainStep(AbstractTrainStep):
+ """
+ T5 train step class.
+
+ Args:
+ args (`argparse.Namespace`): Megatron-LM arguments.
+ """
+
+ def __init__(self, accelerator, args):
+ super().__init__("T5TrainStep")
+ self.get_batch = self.get_batch_func(accelerator, args.megatron_dataset_flag)
+ self.loss_func = self.get_loss_func(accelerator)
+ self.forward_step = self.get_forward_step_func()
+ if not args.model_return_dict:
+ self.model_output_class = None
+ else:
+ from transformers.modeling_outputs import Seq2SeqLMOutput
+
+ self.model_output_class = Seq2SeqLMOutput
+
+ @staticmethod
+ def attn_mask_postprocess(attention_mask):
+ # We create a 3D attention mask from a 2D tensor mask.
+ # [b, 1, s]
+ attention_mask_b1s = attention_mask.unsqueeze(1)
+ # [b, s, 1]
+ attention_mask_bs1 = attention_mask.unsqueeze(2)
+ # [b, s, s]
+ attention_mask_bss = attention_mask_b1s * attention_mask_bs1
+ # Convert attention mask to binary:
+ extended_attention_mask = attention_mask_bss < 0.5
+ return extended_attention_mask
+
+ @staticmethod
+ def get_decoder_mask(seq_length, device):
+ attention_mask = torch.tril(torch.ones((1, seq_length, seq_length), device=device))
+ attention_mask = attention_mask < 0.5
+ return attention_mask
+
+ @staticmethod
+ def get_enc_dec_mask(attention_mask, dec_seq_length, device):
+ batch_size, _ = attention_mask.shape
+ # We create a 3D attention mask from a 2D tensor mask.
+ # [b, 1, s]
+ attention_mask_b1s = attention_mask.unsqueeze(1)
+ # [b, s, 1]
+ attention_mask_bs1 = torch.ones((batch_size, dec_seq_length, 1), device=device)
+ attention_mask_bss = attention_mask_bs1 * attention_mask_b1s
+ extended_attention_mask = attention_mask_bss < 0.5
+ return extended_attention_mask
+
+ def get_batch_func(self, accelerator, megatron_dataset_flag):
+ def get_batch_megatron(data_iterator):
+ """Build the batch."""
+
+ keys = ["text_enc", "text_dec", "labels", "loss_mask", "enc_mask", "dec_mask", "enc_dec_mask"]
+ datatype = torch.int64
+
+ # Broadcast data.
+ if data_iterator is not None:
+ data = next(data_iterator)
+ else:
+ data = None
+ data_b = tensor_parallel.broadcast_data(keys, data, datatype)
+
+ # Unpack.
+ tokens_enc = data_b["text_enc"].long()
+ tokens_dec = data_b["text_dec"].long()
+ labels = data_b["labels"].long()
+ loss_mask = data_b["loss_mask"].float()
+
+ enc_mask = data_b["enc_mask"] < 0.5
+ dec_mask = data_b["dec_mask"] < 0.5
+ enc_dec_mask = data_b["enc_dec_mask"] < 0.5
+
+ return tokens_enc, tokens_dec, loss_mask, labels, enc_mask, dec_mask, enc_dec_mask
+
+ def get_batch_transformer(data_iterator):
+ """Build the batch."""
+ data = next(data_iterator)
+ data = send_to_device(data, torch.cuda.current_device())
+
+ tokens_enc = data["input_ids"].long()
+ labels = data["labels"].long()
+ loss_mask = (labels != -100).to(torch.float)
+ if "decoder_input_ids" in data:
+ tokens_dec = data["decoder_input_ids"].long()
+ else:
+ tokens_dec = labels.new_zeros(labels.shape, device=labels.device, dtype=torch.long)
+ tokens_dec[..., 1:] = labels[..., :-1].clone()
+ tokens_dec[..., 0] = 0
+ tokens_dec.masked_fill_(tokens_dec == -100, 0)
+ enc_mask = T5TrainStep.attn_mask_postprocess(data["attention_mask"].long())
+ dec_mask = T5TrainStep.get_decoder_mask(tokens_dec.shape[1], tokens_dec.device)
+ enc_dec_mask = T5TrainStep.get_enc_dec_mask(
+ data["attention_mask"].long(), tokens_dec.shape[1], tokens_dec.device
+ )
+
+ return tokens_enc, tokens_dec, loss_mask, labels, enc_mask, dec_mask, enc_dec_mask
+
+ if accelerator.state.megatron_lm_plugin.custom_get_batch_function is not None:
+ return accelerator.state.megatron_lm_plugin.custom_get_batch_function
+ if megatron_dataset_flag:
+ try:
+ # Use '--no-use-pep517 -e' to pip install nvidia's megatron from source
+ from pretrain_t5 import get_batch
+
+ return get_batch
+ except ImportError:
+ pass
+ return get_batch_megatron
+ else:
+ return get_batch_transformer
+
+ def get_loss_func(self, accelerator):
+ def loss_func(loss_mask, output_tensor):
+ lm_loss_ = output_tensor.float()
+ lm_loss = torch.sum(lm_loss_.view(-1) * loss_mask.reshape(-1)) / loss_mask.sum()
+
+ loss = lm_loss
+ averaged_losses = average_losses_across_data_parallel_group([lm_loss])
+
+ return loss, {"lm loss": averaged_losses[0]}
+
+ if accelerator.state.megatron_lm_plugin.custom_loss_function is not None:
+ return accelerator.state.megatron_lm_plugin.custom_loss_function
+ return loss_func
+
+ def get_forward_step_func(self):
+ def forward_step(data_iterator, model):
+ """Forward step."""
+ # Get the batch.
+ tokens_enc, tokens_dec, loss_mask, lm_labels, enc_mask, dec_mask, enc_dec_mask = self.get_batch(
+ data_iterator
+ )
+ # Forward model lm_labels
+ output_tensor = model(
+ tokens_enc, tokens_dec, enc_mask, dec_mask, enc_dec_mask, tokentype_ids=None, lm_labels=lm_labels
+ )
+
+ return output_tensor, partial(self.loss_func, loss_mask)
+
+ return forward_step
+
+
+def finish_mpu_init():
+ # torch.distributed initialization
+ args = get_args()
+ # Pytorch distributed.
+ _initialize_distributed()
+
+ # Random seeds for reproducibility.
+ if args.rank == 0:
+ print(f"> setting random seeds to {args.seed} ...")
+ _set_random_seed(args.seed, args.data_parallel_random_init)
+
+
+# initialize megatron setup
+def initialize(accelerator, extra_args_provider=None, args_defaults={}):
+ accelerator.print("Initializing Megatron-LM")
+ assert torch.cuda.is_available(), "Megatron requires CUDA."
+
+ # Parse arguments
+ args = parse_args(extra_args_provider, ignore_unknown_args=True)
+
+ # Set defaults
+ for key, value in args_defaults.items():
+ if getattr(args, key, None) is not None:
+ if args.rank == 0:
+ print(
+ f"WARNING: overriding default arguments for {key}:{getattr(args, key)} with {key}:{value}",
+ flush=True,
+ )
+ setattr(args, key, value)
+
+ if args.use_checkpoint_args or args_defaults.get("use_checkpoint_args", False):
+ assert args.load is not None, "--use-checkpoints-args requires --load argument"
+ load_args_from_checkpoint(args)
+
+ validate_args(args)
+
+ # set global args, build tokenizer, and set adlr-autoresume,
+ # tensorboard-writer, and timers.
+ set_global_variables(args)
+
+ # Megatron's MPU is the master. Complete initialization right away.
+ finish_mpu_init()
+
+ # Autoresume.
+ _init_autoresume()
+
+ # Compile dependencies.
+ _compile_dependencies()
+
+ # Set pytorch JIT layer fusion options and warmup JIT functions.
+ set_jit_fusion_options()
+ args = get_args()
+ if getattr(args, "padded_vocab_size", None) is None:
+ args.padded_vocab_size = _vocab_size_with_padding(args.orig_vocab_size, args)
+ if args.model_type_name == "bert" and args.pretraining_flag and args.num_labels == 2:
+ args.bert_binary_head = True
+ else:
+ args.bert_binary_head = False
+ args.iteration = 0
+
+
+class MegatronEngine(torch.nn.Module):
+ """
+ Megatron-LM model wrapper
+
+ Args:
+ accelerator (:class:`~accelerate.Accelerator`): The accelerator object to use.
+ model: Megatron-LM model
+ optimizer: Megatron-LM optimizer
+ lr_scheduler: Megatron-LM lr scheduler
+ """
+
+ def __init__(self, accelerator, model, optimizer, scheduler):
+ super().__init__()
+ self.module = model
+ self.base_model = model[0]
+ self.optimizer = optimizer
+ self.scheduler = scheduler
+ args = get_args()
+ if accelerator.state.megatron_lm_plugin.custom_train_step_class is not None:
+ self.train_step_handler = accelerator.state.megatron_lm_plugin.custom_train_step_class(
+ args, **accelerator.state.megatron_lm_plugin.custom_train_step_kwargs
+ )
+ elif args.model_type_name == "bert":
+ self.train_step_handler = BertTrainStep(accelerator, args)
+ elif args.model_type_name == "gpt":
+ self.train_step_handler = GPTTrainStep(accelerator, args)
+ elif args.model_type_name == "t5":
+ self.train_step_handler = T5TrainStep(accelerator, args)
+ else:
+ raise ValueError(f"Unsupported model type: {args.model_type_name}")
+ self.optimizer.skipped_iter = False
+
+ # Tracking loss.
+ self.total_loss_dict = {}
+ self.eval_total_loss_dict = {}
+ self.iteration = 0
+ self.report_memory_flag = True
+ self.num_floating_point_operations_so_far = 0
+ self.module_config = None
+ if args.tensorboard_dir is not None:
+ write_args_to_tensorboard()
+
+ def get_module_config(self):
+ args = get_args()
+ config = get_model_config(self.module[0])
+ # Setup some training config params
+ config.grad_scale_func = self.optimizer.scale_loss
+ if isinstance(self.module[0], LocalDDP) and args.overlap_grad_reduce:
+ assert config.no_sync_func is None, (
+ "When overlap_grad_reduce is True, config.no_sync_func must be None; "
+ "a custom no_sync_func is not supported when overlapping grad-reduce"
+ )
+ config.no_sync_func = [model_chunk.no_sync for model_chunk in self.module]
+ if len(self.module) == 1:
+ config.no_sync_func = config.no_sync_func[0]
+ if args.delay_grad_reduce:
+ config.grad_sync_func = [model_chunk.start_grad_sync for model_chunk in self.module]
+ if len(self.module) == 1:
+ config.grad_sync_func = config.grad_sync_func[0]
+ if args.overlap_param_gather and args.delay_param_gather:
+ config.param_sync_func = [
+ lambda x: self.optimizer.finish_param_sync(model_index, x) for model_index in range(len(self.module))
+ ]
+ if len(self.module) == 1:
+ config.param_sync_func = config.param_sync_func[0]
+ config.finalize_model_grads_func = finalize_model_grads
+ return config
+
+ def train(self):
+ for model_module in self.module:
+ model_module.train()
+
+ if self.module_config is None:
+ self.module_config = self.get_module_config()
+
+ self.log_eval_results()
+
+ def eval(self):
+ for model_module in self.module:
+ model_module.eval()
+
+ if self.module_config is None:
+ self.module_config = self.get_module_config()
+
+ def get_batch_data_iterator(self, batch_data):
+ args = get_args()
+ data_chunks = []
+ if len(batch_data) > 0:
+ if args.num_micro_batches > 1:
+ for i in range(0, args.num_micro_batches):
+ data_chunks.append(
+ {
+ k: v[i * args.micro_batch_size : (i + 1) * args.micro_batch_size]
+ for k, v in batch_data.items()
+ }
+ )
+ else:
+ data_chunks = [batch_data]
+
+ if len(self.module) > 1:
+ batch_data_iterator = (
+ [iter(data_chunks) for _ in range(len(self.module))]
+ if len(batch_data) > 0
+ else [None] * len(self.module)
+ )
+ else:
+ batch_data_iterator = iter(data_chunks) if len(batch_data) > 0 else None
+ return batch_data_iterator
+
+ def train_step(self, **batch_data):
+ """
+ Training step for Megatron-LM
+
+ Args:
+ batch_data (:obj:`dict`): The batch data to train on.
+ """
+
+ batch_data_iterator = self.get_batch_data_iterator(batch_data)
+
+ loss_reduced, skipped_iter, grad_norm, num_zeros_in_grad = train_step(
+ forward_step_func=self.train_step_handler.forward_step,
+ data_iterator=batch_data_iterator,
+ model=self.module,
+ optimizer=self.optimizer,
+ opt_param_scheduler=self.scheduler,
+ config=self.module_config,
+ )
+
+ self.optimizer.skipped_iter = skipped_iter == 1
+
+ return loss_reduced, skipped_iter, grad_norm, num_zeros_in_grad
+
+ def eval_step(self, **batch_data):
+ """
+ Evaluation step for Megatron-LM
+
+ Args:
+ batch_data (:obj:`dict`): The batch data to evaluate on.
+ """
+
+ args = get_args()
+ batch_data_iterator = self.get_batch_data_iterator(batch_data)
+ forward_backward_func = get_forward_backward_func()
+ loss_dicts = forward_backward_func(
+ forward_step_func=self.train_step_handler.forward_step,
+ data_iterator=batch_data_iterator,
+ model=self.module,
+ num_microbatches=get_num_microbatches(),
+ seq_length=args.seq_length,
+ micro_batch_size=args.micro_batch_size,
+ forward_only=True,
+ )
+ # Empty unused memory
+ if args.empty_unused_memory_level >= 1:
+ torch.cuda.empty_cache()
+
+ args.consumed_valid_samples += (
+ mpu.get_data_parallel_world_size() * args.micro_batch_size * get_num_microbatches()
+ )
+
+ if mpu.is_pipeline_last_stage(ignore_virtual=True):
+ # Average loss across microbatches.
+ loss_reduced = {}
+ for key in loss_dicts[0]:
+ losses_reduced_for_key = [x[key] for x in loss_dicts]
+ if len(losses_reduced_for_key[0].shape) == 0:
+ loss_reduced[key] = sum(losses_reduced_for_key) / len(losses_reduced_for_key)
+ else:
+ loss_reduced[key] = torch.concat(losses_reduced_for_key)
+ return loss_reduced
+ return {}
+
+ def forward(self, **batch_data):
+ # During training, we use train_step()
+ # model(**batch_data) performs following operations by delegating it to `self.train_step`:
+ # 1. Prepare **batch_data for Tendor, Pipeline and Model Parallelism
+ # 2. Set grad to zero.
+ # 3. forward pass and backward pass using Pipeline Parallelism
+ # 4. Empty unused memory.
+ # 5. Reduce gradients.
+ # 6. Update parameters.
+ # 7. Gather params when using Distributed Optimizer (Data Parallelism).
+ # 8. Update learning rate if scheduler is specified.
+ # 9. Empty unused memory.
+ # 10. Average loss across microbatches and across DP ranks.
+ #
+ # During evaluation, we use eval_step()
+ args = get_args()
+ if self.module[0].training:
+ loss_dict, skipped_iter, grad_norm, num_zeros_in_grad = self.train_step(**batch_data)
+ self.iteration += 1
+ batch_size = mpu.get_data_parallel_world_size() * args.micro_batch_size * get_num_microbatches()
+ args.consumed_train_samples += batch_size
+ self.num_floating_point_operations_so_far += num_floating_point_operations(args, batch_size)
+ if args.tensorboard_dir is not None:
+ # Logging.
+ loss_scale = self.optimizer.get_loss_scale().item()
+ params_norm = None
+ if args.log_params_norm:
+ params_norm = calc_params_l2_norm(self.model)
+ self.report_memory_flag = training_log(
+ loss_dict,
+ self.total_loss_dict,
+ self.optimizer.param_groups[0]["lr"],
+ self.iteration,
+ loss_scale,
+ self.report_memory_flag,
+ skipped_iter,
+ grad_norm,
+ params_norm,
+ num_zeros_in_grad,
+ )
+ else:
+ loss_dict = self.eval_step(**batch_data)
+ if args.tensorboard_dir is not None:
+ for key in loss_dict:
+ self.eval_total_loss_dict[key] = (
+ self.eval_total_loss_dict.get(key, torch.cuda.FloatTensor([0.0])) + loss_dict[key]
+ )
+ self.eval_total_loss_dict[key + "_num_iters"] = self.eval_total_loss_dict.get(
+ key + "_num_iters", torch.cuda.FloatTensor([0.0])
+ ) + torch.cuda.FloatTensor([1.0])
+
+ loss = torch.tensor(0.0, device=torch.cuda.current_device())
+ for key in loss_dict:
+ if len(loss_dict[key].shape) == 0:
+ loss += loss_dict[key]
+
+ logits = None
+ if "logits" in loss_dict:
+ logits = loss_dict["logits"]
+ if self.train_step_handler.model_output_class is not None:
+ return self.train_step_handler.model_output_class(loss=loss, logits=logits)
+ return loss
+
+ def log_eval_results(self):
+ args = get_args()
+ if args.tensorboard_dir is None or self.iteration == 0:
+ return
+ args = get_args()
+ writer = get_tensorboard_writer()
+ string = f"validation loss at iteration {self.iteration} | "
+ for key in self.eval_total_loss_dict:
+ if key.endswith("_num_iters"):
+ continue
+ value = self.eval_total_loss_dict[key] / self.eval_total_loss_dict[key + "_num_iters"]
+ string += f"{key} value: {value} | "
+ ppl = math.exp(min(20, value.item()))
+ if args.pretraining_flag:
+ string += f"{key} PPL: {ppl} | "
+ if writer:
+ writer.add_scalar(f"{key} validation", value.item(), self.iteration)
+ if args.pretraining_flag:
+ writer.add_scalar(f"{key} validation ppl", ppl, self.iteration)
+
+ length = len(string) + 1
+ print_rank_last("-" * length)
+ print_rank_last(string)
+ print_rank_last("-" * length)
+ self.eval_total_loss_dict = {}
+
+ def save_checkpoint(self, output_dir):
+ self.log_eval_results()
+ args = get_args()
+ args.save = output_dir
+ torch.distributed.barrier()
+ save_checkpoint(
+ self.iteration,
+ self.module,
+ self.optimizer,
+ self.scheduler,
+ num_floating_point_operations_so_far=self.num_floating_point_operations_so_far,
+ )
+ torch.distributed.barrier()
+
+ def load_checkpoint(self, input_dir):
+ args = get_args()
+ args.load = input_dir
+ args.consumed_train_samples = 0
+ args.consumed_valid_samples = 0
+ torch.distributed.barrier()
+ iteration, num_floating_point_operations_so_far = load_checkpoint(self.module, self.optimizer, self.scheduler)
+ torch.distributed.barrier()
+ self.iteration = iteration
+ self.num_floating_point_operations_so_far = num_floating_point_operations_so_far
+ if args.fp16 and self.iteration == 0:
+ self.optimizer.reload_model_params()
+
+ def megatron_generate(
+ self,
+ inputs,
+ attention_mask=None,
+ max_length=None,
+ max_new_tokens=None,
+ num_beams=None,
+ temperature=None,
+ top_k=None,
+ top_p=None,
+ length_penalty=None,
+ **kwargs,
+ ):
+ """
+ Generate method for GPT2 model. This method is used for inference. Supports both greedy and beam search along
+ with sampling. Refer the Megatron-LM repo for more details
+
+ Args:
+ inputs (torch.Tensor): input ids
+ attention_mask (torch.Tensor, optional): attention mask. Defaults to None.
+ max_length (int, optional): max length of the generated sequence. Defaults to None.
+ Either this or max_new_tokens should be provided.
+ max_new_tokens (int, optional): max number of tokens to be generated. Defaults to None.
+ Either this or max_length should be provided.
+ num_beams (int, optional): number of beams to use for beam search. Defaults to None.
+ temperature (float, optional): temperature for sampling. Defaults to 1.0.
+ top_k (int, optional): top k tokens to consider for sampling. Defaults to 0.0.
+ top_p (float, optional): tokens in top p probability are considered for sampling. Defaults to 0.0.
+ length_penalty (float, optional): length penalty for beam search. Defaults to None.
+ kwargs: additional key-value arguments
+ """
+
+ # checking if required arguments are passed
+ args = get_args()
+ if args.model_type_name != "gpt":
+ raise NotImplementedError("Generate method is not implemented for this model")
+
+ if args.data_parallel_size > 1:
+ raise ValueError("Generate method requires data parallelism to be 1")
+
+ if args.sequence_parallel:
+ raise ValueError("Generate method requires sequence parallelism to be False")
+
+ if args.recompute_granularity is not None:
+ raise ValueError("Checkpoint activations cannot be set for inference")
+
+ if args.vocab_file is None:
+ raise ValueError("Vocab file is required for inference")
+
+ # Prepare inputs
+ if max_length is None and max_new_tokens is None:
+ raise ValueError("`max_length` or `max_new_tokens` are required for inference")
+
+ if temperature is None:
+ temperature = 1.0
+ elif not (0.0 < temperature <= 100.0):
+ raise ValueError("temperature must be a positive number less than or equal to 100.0")
+
+ if top_k is None:
+ top_k = 0
+ elif not (0 <= top_k <= 1000):
+ raise ValueError("top_k must be a positive number less than or equal to 1000")
+
+ if top_p is None:
+ top_p = 0.0
+ elif top_p > 0.0 and top_k > 0.0:
+ raise ValueError("top_p and top_k sampling cannot be set together")
+ else:
+ if not (0.0 <= top_p <= 1.0):
+ raise ValueError("top_p must be less than or equal to 1.0")
+
+ top_p_decay = kwargs.get("top_p_decay", 0.0)
+ if not (0.0 <= top_p_decay <= 1.0):
+ raise ValueError("top_p_decay must be less than or equal to 1.0")
+
+ top_p_bound = kwargs.get("top_p_bound", 0.0)
+ if not (0.0 <= top_p_bound <= 1.0):
+ raise ValueError("top_p_bound must be less than or equal to 1.0")
+
+ add_BOS = kwargs.get("add_BOS", False)
+ if not (isinstance(add_BOS, bool)):
+ raise ValueError("add_BOS must be a boolean")
+
+ beam_width = num_beams
+ if beam_width is not None:
+ if not isinstance(beam_width, int):
+ raise ValueError("beam_width must be an integer")
+ if beam_width < 1:
+ raise ValueError("beam_width must be greater than 0")
+ if inputs.shape[0] > 1:
+ return "When doing beam_search, batch size must be 1"
+
+ tokenizer = get_tokenizer()
+
+ stop_token = kwargs.get("stop_token", tokenizer.eod)
+ if stop_token is not None:
+ if not isinstance(stop_token, int):
+ raise ValueError("stop_token must be an integer")
+
+ if length_penalty is None:
+ length_penalty = 1.0
+
+ sizes_list = None
+ prompts_tokens_tensor = None
+ prompts_length_tensor = None
+ if torch.distributed.get_rank() == 0:
+ # Get the prompts length.
+ if attention_mask is None:
+ prompts_length_tensor = torch.cuda.LongTensor([inputs.shape[1]] * inputs.shape[0])
+ else:
+ prompts_length_tensor = attention_mask.sum(axis=-1).cuda()
+
+ if max_new_tokens is None:
+ max_new_tokens = max_length - inputs.shape[1]
+ if max_new_tokens <= 0:
+ raise ValueError("max_new_tokens must be greater than 0")
+
+ if add_BOS:
+ max_length = max_new_tokens + inputs.shape[1] + 1
+ # making sure that `max_length` is a multiple of 4 to leverage fused kernels
+ max_length = 4 * math.ceil(max_length / 4)
+ max_new_tokens = max_length - (inputs.shape[1] + 1)
+ padding = torch.cuda.LongTensor([[tokenizer.eod] * max_new_tokens] * inputs.shape[0])
+ prompts_tokens_tensor = torch.concat(
+ [torch.unsqueeze(padding[:, 0], axis=-1), inputs.cuda(), padding], axis=-1
+ )
+ else:
+ # making sure that `max_length` is a multiple of 4 to leverage fused kernels
+ max_length = max_new_tokens + inputs.shape[1]
+ max_length = 4 * math.ceil(max_length / 4)
+ max_new_tokens = max_length - inputs.shape[1]
+ padding = torch.cuda.LongTensor([[tokenizer.eod] * max_new_tokens] * inputs.shape[0])
+ prompts_tokens_tensor = torch.concat([inputs.cuda(), padding], axis=-1)
+
+ # We need the sizes of these tensors for the broadcast
+ sizes_list = [
+ prompts_tokens_tensor.size(0), # Batch size
+ prompts_tokens_tensor.size(1),
+ ] # Sequence length
+
+ # First, broadcast the sizes.
+ sizes_tensor = broadcast_int_list(2, int_list=sizes_list, rank=0)
+
+ # Now that we have the sizes, we can broadcast the tokens
+ # and length tensors.
+ sizes = sizes_tensor.tolist()
+ context_tokens_tensor = broadcast_tensor(sizes, torch.int64, tensor=prompts_tokens_tensor, rank=0)
+ context_length_tensor = broadcast_tensor(sizes[0], torch.int64, tensor=prompts_length_tensor, rank=0)
+
+ # Run the inference
+ random_seed = kwargs.get("random_seed", 0)
+ torch.random.manual_seed(random_seed)
+ unwrapped_model = unwrap_model(self.base_model, (torchDDP, LocalDDP, Float16Module))
+ if beam_width is not None:
+ tokens, _ = beam_search_and_return_on_first_stage(
+ unwrapped_model,
+ context_tokens_tensor,
+ context_length_tensor,
+ beam_width,
+ stop_token=stop_token,
+ num_return_gen=1,
+ length_penalty=length_penalty,
+ )
+ else:
+ tokens, _, _ = generate_tokens_probs_and_return_on_first_stage(
+ unwrapped_model,
+ context_tokens_tensor,
+ context_length_tensor,
+ return_output_log_probs=False,
+ top_k=top_k,
+ top_p=top_p,
+ top_p_decay=top_p_decay,
+ top_p_bound=top_p_bound,
+ temperature=temperature,
+ use_eod_token_for_early_termination=True,
+ )
+ return tokens
+
+
+# other utilities
+def avg_losses_across_data_parallel_group(losses):
+ """
+ Average losses across data parallel group.
+
+ Args:
+ losses (List[Tensor]): List of losses to average across data parallel group.
+ """
+
+ return average_losses_across_data_parallel_group(losses)
+
+
+def gather_across_data_parallel_groups(tensor):
+ """
+ Recursively gather tensor in a nested list/tuple/dictionary of tensors from data parallel ranks.
+
+ Args:
+ tensor (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to gather across data parallel ranks.
+
+ """
+
+ def _gpu_gather_one(tensor):
+ if tensor.ndim == 0:
+ tensor = tensor.clone()[None]
+ output_tensors = [
+ torch.empty_like(tensor)
+ for _ in range(torch.distributed.get_world_size(group=mpu.get_data_parallel_group()))
+ ]
+ torch.distributed.all_gather(output_tensors, tensor, group=mpu.get_data_parallel_group())
+ return torch.cat(output_tensors, dim=0)
+
+ return recursively_apply(_gpu_gather_one, tensor, error_on_other_type=True)
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/memory.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/memory.py
new file mode 100644
index 0000000000000000000000000000000000000000..51b71107e5b1c7209e17948cde889f7d82f56b41
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/memory.py
@@ -0,0 +1,210 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+A collection of utilities for ensuring that training can always occur. Heavily influenced by the
+[toma](https://github.com/BlackHC/toma) library.
+"""
+
+import functools
+import gc
+import importlib
+import inspect
+import warnings
+from typing import Optional
+
+import torch
+from packaging import version
+
+from .imports import (
+ is_cuda_available,
+ is_hpu_available,
+ is_ipex_available,
+ is_mlu_available,
+ is_mps_available,
+ is_musa_available,
+ is_npu_available,
+ is_sdaa_available,
+ is_xpu_available,
+)
+from .versions import compare_versions
+
+
+def clear_device_cache(garbage_collection=False):
+ """
+ Clears the device cache by calling `torch.{backend}.empty_cache`. Can also run `gc.collect()`, but do note that
+ this is a *considerable* slowdown and should be used sparingly.
+ """
+ if garbage_collection:
+ gc.collect()
+
+ if is_xpu_available():
+ torch.xpu.empty_cache()
+ elif is_mlu_available():
+ torch.mlu.empty_cache()
+ elif is_sdaa_available():
+ torch.sdaa.empty_cache()
+ elif is_musa_available():
+ torch.musa.empty_cache()
+ elif is_npu_available():
+ torch.npu.empty_cache()
+ elif is_mps_available(min_version="2.0"):
+ torch.mps.empty_cache()
+ elif is_cuda_available():
+ torch.cuda.empty_cache()
+ elif is_hpu_available():
+ # torch.hpu.empty_cache() # not available on hpu as it reserves all device memory for the current process
+ pass
+
+
+def release_memory(*objects):
+ """
+ Releases memory from `objects` by setting them to `None` and calls `gc.collect()` and `torch.cuda.empty_cache()`.
+ Returned objects should be reassigned to the same variables.
+
+ Args:
+ objects (`Iterable`):
+ An iterable of objects
+ Returns:
+ A list of `None` objects to replace `objects`
+
+ Example:
+
+ ```python
+ >>> import torch
+ >>> from accelerate.utils import release_memory
+
+ >>> a = torch.ones(1000, 1000).cuda()
+ >>> b = torch.ones(1000, 1000).cuda()
+ >>> a, b = release_memory(a, b)
+ ```
+ """
+ if not isinstance(objects, list):
+ objects = list(objects)
+ for i in range(len(objects)):
+ objects[i] = None
+ clear_device_cache(garbage_collection=True)
+ return objects
+
+
+def should_reduce_batch_size(exception: Exception) -> bool:
+ """
+ Checks if `exception` relates to CUDA out-of-memory, XPU out-of-memory, CUDNN not supported, or CPU out-of-memory
+
+ Args:
+ exception (`Exception`):
+ An exception
+ """
+ _statements = [
+ " out of memory.", # OOM for CUDA, HIP, XPU
+ "cuDNN error: CUDNN_STATUS_NOT_SUPPORTED.", # CUDNN SNAFU
+ "DefaultCPUAllocator: can't allocate memory", # CPU OOM
+ "FATAL ERROR :: MODULE:PT_DEVMEM Allocation failed", # HPU OOM
+ ]
+ if isinstance(exception, RuntimeError) and len(exception.args) == 1:
+ return any(err in exception.args[0] for err in _statements)
+ return False
+
+
+def find_executable_batch_size(
+ function: Optional[callable] = None,
+ starting_batch_size: int = 128,
+ reduce_batch_size_fn: Optional[callable] = None,
+):
+ """
+ A basic decorator that will try to execute `function`. If it fails from exceptions related to out-of-memory or
+ CUDNN, the batch size is multiplied by 0.9 and passed to `function`
+
+ `function` must take in a `batch_size` parameter as its first argument.
+
+ Args:
+ function (`callable`, *optional*):
+ A function to wrap
+ starting_batch_size (`int`, *optional*):
+ The batch size to try and fit into memory
+
+ Example:
+
+ ```python
+ >>> from accelerate.utils import find_executable_batch_size
+
+
+ >>> @find_executable_batch_size(starting_batch_size=128)
+ ... def train(batch_size, model, optimizer):
+ ... ...
+
+
+ >>> train(model, optimizer)
+ ```
+ """
+ if function is None:
+ return functools.partial(find_executable_batch_size, starting_batch_size=starting_batch_size)
+
+ batch_size = starting_batch_size
+ if reduce_batch_size_fn is None:
+
+ def reduce_batch_size_fn():
+ nonlocal batch_size
+ batch_size = int(batch_size * 0.9)
+ return batch_size
+
+ def decorator(*args, **kwargs):
+ nonlocal batch_size
+ clear_device_cache(garbage_collection=True)
+ params = list(inspect.signature(function).parameters.keys())
+ # Guard against user error
+ if len(params) < (len(args) + 1):
+ arg_str = ", ".join([f"{arg}={value}" for arg, value in zip(params[1:], args[1:])])
+ raise TypeError(
+ f"Batch size was passed into `{function.__name__}` as the first argument when called."
+ f"Remove this as the decorator already does so: `{function.__name__}({arg_str})`"
+ )
+ while True:
+ if batch_size == 0:
+ raise RuntimeError("No executable batch size found, reached zero.")
+ try:
+ return function(batch_size, *args, **kwargs)
+ except Exception as e:
+ if should_reduce_batch_size(e):
+ clear_device_cache(garbage_collection=True)
+ batch_size = reduce_batch_size_fn()
+ else:
+ raise
+
+ return decorator
+
+
+def get_xpu_available_memory(device_index: int):
+ if version.parse(torch.__version__).release >= version.parse("2.6").release:
+ # torch.xpu.mem_get_info API is available starting from PyTorch 2.6
+ # It further requires PyTorch built with the SYCL runtime which supports API
+ # to query available device memory. If not available, exception will be
+ # raised. Version of SYCL runtime used to build PyTorch is being reported
+ # with print(torch.version.xpu) and corresponds to the version of Intel DPC++
+ # SYCL compiler. First version to support required feature is 20250001.
+ try:
+ return torch.xpu.mem_get_info(device_index)[0]
+ except Exception:
+ pass
+ elif is_ipex_available():
+ ipex_version = version.parse(importlib.metadata.version("intel_extension_for_pytorch"))
+ if compare_versions(ipex_version, ">=", "2.5"):
+ from intel_extension_for_pytorch.xpu import mem_get_info
+
+ return mem_get_info(device_index)[0]
+
+ warnings.warn(
+ "The XPU `mem_get_info` API is available in IPEX version >=2.5 or PyTorch >=2.6. The current returned available memory is incorrect. Please consider upgrading your IPEX or PyTorch version."
+ )
+ return torch.xpu.max_memory_allocated(device_index)
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/modeling.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/modeling.py
new file mode 100644
index 0000000000000000000000000000000000000000..830249ffb1041b6cb29b6e7bdda1d7e47f28bc99
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/modeling.py
@@ -0,0 +1,2186 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import contextlib
+import gc
+import inspect
+import json
+import logging
+import os
+import re
+import shutil
+import tempfile
+import warnings
+from collections import OrderedDict, defaultdict
+from typing import Optional, Union
+
+import torch
+from torch import distributed as dist
+from torch import nn
+
+from ..state import AcceleratorState
+from .constants import SAFE_WEIGHTS_NAME, WEIGHTS_NAME
+from .dataclasses import AutocastKwargs, CustomDtype, DistributedType
+from .imports import (
+ is_hpu_available,
+ is_mlu_available,
+ is_mps_available,
+ is_musa_available,
+ is_npu_available,
+ is_peft_available,
+ is_sdaa_available,
+ is_torch_xla_available,
+ is_xpu_available,
+)
+from .memory import clear_device_cache, get_xpu_available_memory
+from .offload import load_offloaded_weight, offload_weight, save_offload_index
+from .tqdm import is_tqdm_available, tqdm
+from .versions import is_torch_version
+
+
+if is_npu_available(check_device=False):
+ import torch_npu # noqa: F401
+
+if is_mlu_available(check_device=False):
+ import torch_mlu # noqa: F401
+
+if is_sdaa_available(check_device=False):
+ import torch_sdaa # noqa: F401
+
+if is_musa_available(check_device=False):
+ import torch_musa # noqa: F401
+
+from safetensors import safe_open
+from safetensors.torch import load_file as safe_load_file
+
+
+WEIGHTS_INDEX_NAME = "pytorch_model.bin.index.json"
+
+logger = logging.getLogger(__name__)
+
+
+def is_peft_model(model):
+ from .other import extract_model_from_parallel
+
+ if is_peft_available():
+ from peft import PeftModel
+
+ return is_peft_available() and isinstance(extract_model_from_parallel(model), PeftModel)
+
+
+def check_device_same(first_device, second_device):
+ """
+ Utility method to check if two `torch` devices are similar. When dealing with CUDA devices, torch throws `False`
+ for `torch.device("cuda") == torch.device("cuda:0")` whereas they should be the same
+
+ Args:
+ first_device (`torch.device`):
+ First device to check
+ second_device (`torch.device`):
+ Second device to check
+ """
+ if first_device.type != second_device.type:
+ return False
+
+ if first_device.type != "cpu" and first_device.index is None:
+ # In case the first_device is a cuda device and have
+ # the index attribute set to `None`, default it to `0`
+ first_device = torch.device(first_device.type, index=0)
+
+ if second_device.type != "cpu" and second_device.index is None:
+ # In case the second_device is a cuda device and have
+ # the index attribute set to `None`, default it to `0`
+ second_device = torch.device(second_device.type, index=0)
+
+ return first_device == second_device
+
+
+def convert_file_size_to_int(size: Union[int, str]):
+ """
+ Converts a size expressed as a string with digits an unit (like `"5MB"`) to an integer (in bytes).
+
+ Args:
+ size (`int` or `str`): The size to convert. Will be directly returned if an `int`.
+
+ Example:
+
+ ```py
+ >>> convert_file_size_to_int("1MiB")
+ 1048576
+ ```
+ """
+ mem_size = -1
+ err_msg = (
+ f"`size` {size} is not in a valid format. Use an integer for bytes, or a string with an unit (like '5.0GB')."
+ )
+ try:
+ if isinstance(size, int):
+ mem_size = size
+ elif size.upper().endswith("GIB"):
+ mem_size = int(float(size[:-3]) * (2**30))
+ elif size.upper().endswith("MIB"):
+ mem_size = int(float(size[:-3]) * (2**20))
+ elif size.upper().endswith("KIB"):
+ mem_size = int(float(size[:-3]) * (2**10))
+ elif size.upper().endswith("GB"):
+ int_size = int(float(size[:-2]) * (10**9))
+ mem_size = int_size // 8 if size.endswith("b") else int_size
+ elif size.upper().endswith("MB"):
+ int_size = int(float(size[:-2]) * (10**6))
+ mem_size = int_size // 8 if size.endswith("b") else int_size
+ elif size.upper().endswith("KB"):
+ int_size = int(float(size[:-2]) * (10**3))
+ mem_size = int_size // 8 if size.endswith("b") else int_size
+ except ValueError:
+ raise ValueError(err_msg)
+
+ if mem_size < 0:
+ raise ValueError(err_msg)
+ return mem_size
+
+
+def dtype_byte_size(dtype: torch.dtype):
+ """
+ Returns the size (in bytes) occupied by one parameter of type `dtype`.
+
+ Example:
+
+ ```py
+ >>> dtype_byte_size(torch.float32)
+ 4
+ ```
+ """
+ if dtype == torch.bool:
+ return 1 / 8
+ elif dtype == CustomDtype.INT2:
+ return 1 / 4
+ elif dtype == CustomDtype.INT4:
+ return 1 / 2
+ elif dtype == CustomDtype.FP8:
+ return 1
+ elif is_torch_version(">=", "2.1.0") and dtype in [torch.float8_e4m3fn, torch.float8_e5m2]:
+ return 1
+ bit_search = re.search(r"[^\d](\d+)$", str(dtype))
+ if bit_search is None:
+ raise ValueError(f"`dtype` is not a valid dtype: {dtype}.")
+ bit_size = int(bit_search.groups()[0])
+ return bit_size // 8
+
+
+def id_tensor_storage(tensor: torch.Tensor) -> tuple[torch.device, int, int]:
+ """
+ Unique identifier to a tensor storage. Multiple different tensors can share the same underlying storage. For
+ example, "meta" tensors all share the same storage, and thus their identifier will all be equal. This identifier is
+ guaranteed to be unique and constant for this tensor's storage during its lifetime. Two tensor storages with
+ non-overlapping lifetimes may have the same id.
+ """
+ _SIZE = {
+ torch.int64: 8,
+ torch.float32: 4,
+ torch.int32: 4,
+ torch.bfloat16: 2,
+ torch.float16: 2,
+ torch.int16: 2,
+ torch.uint8: 1,
+ torch.int8: 1,
+ torch.bool: 1,
+ torch.float64: 8,
+ }
+ try:
+ storage_ptr = tensor.untyped_storage().data_ptr()
+ storage_size = tensor.untyped_storage().nbytes()
+ except Exception:
+ try:
+ # Fallback for torch==1.10
+ storage_ptr = tensor.storage().data_ptr()
+ storage_size = tensor.storage().size() * _SIZE[tensor.dtype]
+ except NotImplementedError:
+ # Fallback for meta storage
+ storage_ptr = 0
+ # On torch >=2.0 this is the tensor size
+ storage_size = tensor.nelement() * _SIZE[tensor.dtype]
+
+ return tensor.device, storage_ptr, storage_size
+
+
+def set_module_tensor_to_device(
+ module: nn.Module,
+ tensor_name: str,
+ device: Union[int, str, torch.device],
+ value: Optional[torch.Tensor] = None,
+ dtype: Optional[Union[str, torch.dtype]] = None,
+ fp16_statistics: Optional[torch.HalfTensor] = None,
+ tied_params_map: Optional[dict[int, dict[torch.device, torch.Tensor]]] = None,
+ non_blocking: bool = False,
+ clear_cache: bool = True,
+):
+ """
+ A helper function to set a given tensor (parameter of buffer) of a module on a specific device (note that doing
+ `param.to(device)` creates a new tensor not linked to the parameter, which is why we need this function).
+
+ Args:
+ module (`torch.nn.Module`):
+ The module in which the tensor we want to move lives.
+ tensor_name (`str`):
+ The full name of the parameter/buffer.
+ device (`int`, `str` or `torch.device`):
+ The device on which to set the tensor.
+ value (`torch.Tensor`, *optional*):
+ The value of the tensor (useful when going from the meta device to any other device).
+ dtype (`torch.dtype`, *optional*):
+ If passed along the value of the parameter will be cast to this `dtype`. Otherwise, `value` will be cast to
+ the dtype of the existing parameter in the model.
+ fp16_statistics (`torch.HalfTensor`, *optional*):
+ The list of fp16 statistics to set on the module, used for 8 bit model serialization.
+ tied_params_map (Dict[int, Dict[torch.device, torch.Tensor]], *optional*, defaults to `None`):
+ A map of current data pointers to dictionaries of devices to already dispatched tied weights. For a given
+ execution device, this parameter is useful to reuse the first available pointer of a shared weight on the
+ device for all others, instead of duplicating memory.
+ non_blocking (`bool`, *optional*, defaults to `False`):
+ If `True`, the device transfer will be asynchronous with respect to the host, if possible.
+ clear_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not to clear the device cache after setting the tensor on the device.
+ """
+ # Recurse if needed
+ if "." in tensor_name:
+ splits = tensor_name.split(".")
+ for split in splits[:-1]:
+ new_module = getattr(module, split)
+ if new_module is None:
+ raise ValueError(f"{module} has no attribute {split}.")
+ module = new_module
+ tensor_name = splits[-1]
+
+ if tensor_name not in module._parameters and tensor_name not in module._buffers:
+ raise ValueError(f"{module} does not have a parameter or a buffer named {tensor_name}.")
+ is_buffer = tensor_name in module._buffers
+ old_value = getattr(module, tensor_name)
+
+ # Treat the case where old_value (or a custom `value`, typically offloaded to RAM/disk) belongs to a tied group, and one of the weight
+ # in the tied group has already been dispatched to the device, by avoiding reallocating memory on the device and just copying the pointer.
+ if (
+ value is not None
+ and tied_params_map is not None
+ and value.data_ptr() in tied_params_map
+ and device in tied_params_map[value.data_ptr()]
+ ):
+ module._parameters[tensor_name] = tied_params_map[value.data_ptr()][device]
+ return
+ elif (
+ tied_params_map is not None
+ and old_value.data_ptr() in tied_params_map
+ and device in tied_params_map[old_value.data_ptr()]
+ ):
+ module._parameters[tensor_name] = tied_params_map[old_value.data_ptr()][device]
+ return
+
+ if old_value.device == torch.device("meta") and device not in ["meta", torch.device("meta")] and value is None:
+ raise ValueError(f"{tensor_name} is on the meta device, we need a `value` to put in on {device}.")
+
+ param = module._parameters[tensor_name] if tensor_name in module._parameters else None
+ param_cls = type(param)
+
+ if value is not None:
+ # We can expect mismatches when using bnb 4bit since Params4bit will reshape and pack the weights.
+ # In other cases, we want to make sure we're not loading checkpoints that do not match the config.
+ if old_value.shape != value.shape and param_cls.__name__ != "Params4bit":
+ raise ValueError(
+ f'Trying to set a tensor of shape {value.shape} in "{tensor_name}" (which has shape {old_value.shape}), this looks incorrect.'
+ )
+
+ if dtype is None:
+ # For compatibility with PyTorch load_state_dict which converts state dict dtype to existing dtype in model
+ value = value.to(old_value.dtype, non_blocking=non_blocking)
+ elif not str(value.dtype).startswith(("torch.uint", "torch.int", "torch.bool")):
+ value = value.to(dtype, non_blocking=non_blocking)
+
+ device_quantization = None
+ with torch.no_grad():
+ # leave it on cpu first before moving them to cuda
+ # # fix the case where the device is meta, we don't want to put it on cpu because there is no data =0
+ if (
+ param is not None
+ and param.device.type not in ("cuda", "xpu")
+ and torch.device(device).type in ("cuda", "xpu")
+ and param_cls.__name__ in ["Int8Params", "FP4Params", "Params4bit"]
+ ):
+ device_quantization = device
+ device = "cpu"
+ # `torch.Tensor.to()` is not supported by `torch_npu` (see this [issue](https://github.com/Ascend/pytorch/issues/16)).
+ if isinstance(device, int):
+ if is_npu_available():
+ device = f"npu:{device}"
+ elif is_mlu_available():
+ device = f"mlu:{device}"
+ elif is_sdaa_available():
+ device = f"sdaa:{device}"
+ elif is_musa_available():
+ device = f"musa:{device}"
+ elif is_hpu_available():
+ device = "hpu"
+ if "xpu" in str(device) and not is_xpu_available():
+ raise ValueError(f'{device} is not available, you should use device="cpu" instead')
+ if value is None:
+ new_value = old_value.to(device, non_blocking=non_blocking)
+ if dtype is not None and device in ["meta", torch.device("meta")]:
+ if not str(old_value.dtype).startswith(("torch.uint", "torch.int", "torch.bool")):
+ new_value = new_value.to(dtype, non_blocking=non_blocking)
+
+ if not is_buffer:
+ module._parameters[tensor_name] = param_cls(new_value, requires_grad=old_value.requires_grad)
+ elif isinstance(value, torch.Tensor):
+ new_value = value.to(device, non_blocking=non_blocking)
+ else:
+ new_value = torch.tensor(value, device=device)
+ if device_quantization is not None:
+ device = device_quantization
+ if is_buffer:
+ module._buffers[tensor_name] = new_value
+ elif value is not None or not check_device_same(torch.device(device), module._parameters[tensor_name].device):
+ param_cls = type(module._parameters[tensor_name])
+ kwargs = module._parameters[tensor_name].__dict__
+ if param_cls.__name__ in ["Int8Params", "FP4Params", "Params4bit"]:
+ if param_cls.__name__ == "Int8Params" and new_value.dtype == torch.float32:
+ # downcast to fp16 if any - needed for 8bit serialization
+ new_value = new_value.to(torch.float16, non_blocking=non_blocking)
+ # quantize module that are going to stay on the cpu so that we offload quantized weights
+ if device == "cpu" and param_cls.__name__ == "Int8Params":
+ new_value = param_cls(new_value, requires_grad=old_value.requires_grad, **kwargs).to(0).to("cpu")
+ new_value.CB = new_value.CB.to("cpu")
+ new_value.SCB = new_value.SCB.to("cpu")
+ else:
+ new_value = param_cls(new_value, requires_grad=old_value.requires_grad, **kwargs).to(
+ device, non_blocking=non_blocking
+ )
+ elif param_cls.__name__ in ["QTensor", "QBitsTensor"]:
+ new_value = torch.nn.Parameter(new_value, requires_grad=old_value.requires_grad).to(
+ device, non_blocking=non_blocking
+ )
+ elif param_cls.__name__ in ["AffineQuantizedTensor"]:
+ new_value = new_value.to(device, non_blocking=non_blocking)
+ else:
+ new_value = param_cls(new_value, requires_grad=old_value.requires_grad).to(
+ device, non_blocking=non_blocking
+ )
+
+ module._parameters[tensor_name] = new_value
+ if fp16_statistics is not None:
+ module._parameters[tensor_name].SCB = fp16_statistics.to(device, non_blocking=non_blocking)
+ del fp16_statistics
+ # as we put the weight to meta, it doesn't have SCB attr anymore. make sure that it is not a meta weight
+ if (
+ module.__class__.__name__ == "Linear8bitLt"
+ and getattr(module.weight, "SCB", None) is None
+ and str(module.weight.device) != "meta"
+ ):
+ # quantize only if necessary
+ device_index = torch.device(device).index if torch.device(device).type == "cuda" else None
+ if not getattr(module.weight, "SCB", None) and device_index is not None:
+ if module.bias is not None and module.bias.device.type != "meta":
+ # if a bias exists, we need to wait until the bias is set on the correct device
+ module = module.cuda(device_index)
+ elif module.bias is None:
+ # if no bias exists, we can quantize right away
+ module = module.cuda(device_index)
+ elif (
+ module.__class__.__name__ == "Linear4bit"
+ and getattr(module.weight, "quant_state", None) is None
+ and str(module.weight.device) != "meta"
+ ):
+ # quantize only if necessary
+ device_index = torch.device(device).index if torch.device(device).type == "cuda" else None
+ if not getattr(module.weight, "quant_state", None) and device_index is not None:
+ module.weight = module.weight.cuda(device_index)
+
+ # clean pre and post forward hook
+ if clear_cache and device not in ("cpu", "meta"):
+ clear_device_cache()
+
+ # When handling tied weights, we update tied_params_map to keep track of the tied weights that have already been allocated on the device in
+ # order to avoid duplicating memory, see above.
+ if (
+ tied_params_map is not None
+ and old_value.data_ptr() in tied_params_map
+ and device not in tied_params_map[old_value.data_ptr()]
+ ):
+ tied_params_map[old_value.data_ptr()][device] = new_value
+ elif (
+ value is not None
+ and tied_params_map is not None
+ and value.data_ptr() in tied_params_map
+ and device not in tied_params_map[value.data_ptr()]
+ ):
+ tied_params_map[value.data_ptr()][device] = new_value
+
+
+def named_module_tensors(
+ module: nn.Module, include_buffers: bool = True, recurse: bool = False, remove_non_persistent: bool = False
+):
+ """
+ A helper function that gathers all the tensors (parameters + buffers) of a given module. If `include_buffers=True`
+ it's the same as doing `module.named_parameters(recurse=recurse) + module.named_buffers(recurse=recurse)`.
+
+ Args:
+ module (`torch.nn.Module`):
+ The module we want the tensors on.
+ include_buffer (`bool`, *optional*, defaults to `True`):
+ Whether or not to include the buffers in the result.
+ recurse (`bool`, *optional`, defaults to `False`):
+ Whether or not to go look in every submodule or just return the direct parameters and buffers.
+ remove_non_persistent (`bool`, *optional*, defaults to `False`):
+ Whether or not to remove the non persistent buffer from the buffers. Useful only when include_buffers =
+ True
+ """
+ yield from module.named_parameters(recurse=recurse)
+
+ if include_buffers:
+ non_persistent_buffers = set()
+ if remove_non_persistent:
+ non_persistent_buffers = get_non_persistent_buffers(module, recurse=recurse)
+ for named_buffer in module.named_buffers(recurse=recurse):
+ name, _ = named_buffer
+ if name not in non_persistent_buffers:
+ yield named_buffer
+
+
+def get_non_persistent_buffers(module: nn.Module, recurse: bool = False, fqns: bool = False):
+ """
+ Gather all non persistent buffers of a given modules into a set
+
+ Args:
+ module (`nn.Module`):
+ The module we want the non persistent buffers on.
+ recurse (`bool`, *optional*, defaults to `False`):
+ Whether or not to go look in every submodule or just return the direct non persistent buffers.
+ fqns (`bool`, *optional*, defaults to `False`):
+ Whether or not to return the fully-qualified names of the non persistent buffers.
+ """
+
+ non_persistent_buffers_set = module._non_persistent_buffers_set
+ if recurse:
+ for n, m in module.named_modules():
+ if fqns:
+ non_persistent_buffers_set |= {n + "." + b for b in m._non_persistent_buffers_set}
+ else:
+ non_persistent_buffers_set |= m._non_persistent_buffers_set
+
+ return non_persistent_buffers_set
+
+
+def check_tied_parameters_in_config(model: nn.Module):
+ """
+ Check if there is any indication in the given model that some weights should be tied.
+
+ Args:
+ model (`torch.nn.Module`): The model to inspect
+
+ Returns:
+ bool: True if the model needs to have tied weights
+ """
+
+ # based on model.tie_weights() method
+ has_tied_word_embedding = False
+ has_tied_encoder_decoder = False
+ has_tied_module = False
+
+ if "PreTrainedModel" in [c.__name__ for c in inspect.getmro(model.__class__)]:
+ has_tied_word_embedding = False
+ model_decoder_config = None
+ if hasattr(model, "config"):
+ model_decoder_config = (
+ model.config.get_text_config(decoder=True)
+ if hasattr(model.config, "get_text_config")
+ else model.config
+ )
+ has_tied_word_embedding = (
+ model_decoder_config is not None
+ and getattr(model_decoder_config, "tie_word_embeddings", False)
+ and model.get_output_embeddings()
+ )
+
+ has_tied_encoder_decoder = (
+ hasattr(model, "config")
+ and getattr(model.config, "is_encoder_decoder", False)
+ and getattr(model.config, "tie_encoder_decoder", False)
+ )
+ has_tied_module = any(hasattr(module, "_tie_weights") for module in model.modules())
+ return any([has_tied_word_embedding, has_tied_encoder_decoder, has_tied_module])
+
+
+def _get_param_device(param, device_map):
+ if param in device_map:
+ return device_map[param]
+ parent_param = ".".join(param.split(".")[:-1])
+ if parent_param == param:
+ raise ValueError(f"The `device_map` does not contain the module {param}.")
+ else:
+ return _get_param_device(parent_param, device_map)
+
+
+def check_tied_parameters_on_same_device(tied_params, device_map):
+ """
+ Check if tied parameters are on the same device
+
+ Args:
+ tied_params (`List[List[str]]`):
+ A list of lists of parameter names being all tied together.
+
+ device_map (`Dict[str, Union[int, str, torch.device]]`):
+ A map that specifies where each submodule should go.
+
+ """
+ for tie_param in tied_params:
+ tie_param_devices = {}
+ for param in tie_param:
+ tie_param_devices[param] = _get_param_device(param, device_map)
+ if len(set(tie_param_devices.values())) > 1:
+ logger.warning(
+ f"Tied parameters are on different devices: {tie_param_devices}. "
+ "Please modify your custom device map or set `device_map='auto'`. "
+ )
+
+
+def find_tied_parameters(model: torch.nn.Module, **kwargs) -> list[list[str]]:
+ """
+ Find the tied parameters in a given model.
+
+
+
+ The signature accepts keyword arguments, but they are for the recursive part of this function and you should ignore
+ them.
+
+
+
+ Args:
+ model (`torch.nn.Module`): The model to inspect.
+
+ Returns:
+ List[List[str]]: A list of lists of parameter names being all tied together.
+
+ Example:
+
+ ```py
+ >>> from collections import OrderedDict
+ >>> import torch.nn as nn
+
+ >>> model = nn.Sequential(OrderedDict([("linear1", nn.Linear(4, 4)), ("linear2", nn.Linear(4, 4))]))
+ >>> model.linear2.weight = model.linear1.weight
+ >>> find_tied_parameters(model)
+ [['linear1.weight', 'linear2.weight']]
+ ```
+ """
+
+ # get ALL model parameters and their names
+ all_named_parameters = {name: param for name, param in model.named_parameters(remove_duplicate=False)}
+
+ # get ONLY unique named parameters,
+ # if parameter is tied and have multiple names, it will be included only once
+ no_duplicate_named_parameters = {name: param for name, param in model.named_parameters(remove_duplicate=True)}
+
+ # the difference of the two sets will give us the tied parameters
+ tied_param_names = set(all_named_parameters.keys()) - set(no_duplicate_named_parameters.keys())
+
+ # 'tied_param_names' contains the names of parameters that are tied in the model, but we do not know
+ # which names refer to the same parameter. To identify this, we need to group them together.
+ tied_param_groups = {}
+ for tied_param_name in tied_param_names:
+ tied_param = all_named_parameters[tied_param_name]
+ for param_name, param in no_duplicate_named_parameters.items():
+ # compare if parameters are the same, if so, group their names together
+ if param is tied_param:
+ if param_name not in tied_param_groups:
+ tied_param_groups[param_name] = []
+ tied_param_groups[param_name].append(tied_param_name)
+
+ return [sorted([weight] + list(set(tied))) for weight, tied in tied_param_groups.items()]
+
+
+def retie_parameters(model, tied_params):
+ """
+ Reties tied parameters in a given model if the link was broken (for instance when adding hooks).
+
+ Args:
+ model (`torch.nn.Module`):
+ The model in which to retie parameters.
+ tied_params (`List[List[str]]`):
+ A mapping parameter name to tied parameter name as obtained by `find_tied_parameters`.
+ """
+ for tied_group in tied_params:
+ param_to_tie = None
+ # two loops : the first one to set param_to_tie , the second one to change the values of tied_group
+ for param_name in tied_group:
+ module = model
+ splits = param_name.split(".")
+ for split in splits[:-1]:
+ module = getattr(module, split)
+ param = getattr(module, splits[-1])
+ if param_to_tie is None and param.device != torch.device("meta"):
+ param_to_tie = param
+ break
+ if param_to_tie is not None:
+ for param_name in tied_group:
+ module = model
+ splits = param_name.split(".")
+ for split in splits[:-1]:
+ module = getattr(module, split)
+ setattr(module, splits[-1], param_to_tie)
+
+
+def _get_proper_dtype(dtype: Union[str, torch.device]) -> torch.dtype:
+ """
+ Just does torch.dtype(dtype) if necessary.
+ """
+ if isinstance(dtype, str):
+ # We accept "torch.float16" or just "float16"
+ dtype = dtype.replace("torch.", "")
+ dtype = getattr(torch, dtype)
+ return dtype
+
+
+def compute_module_sizes(
+ model: nn.Module,
+ dtype: Optional[Union[str, torch.device]] = None,
+ special_dtypes: Optional[dict[str, Union[str, torch.device]]] = None,
+ buffers_only: bool = False,
+):
+ """
+ Compute the size of each submodule of a given model.
+ """
+ if dtype is not None:
+ dtype = _get_proper_dtype(dtype)
+ dtype_size = dtype_byte_size(dtype)
+ if special_dtypes is not None:
+ special_dtypes = {key: _get_proper_dtype(dtyp) for key, dtyp in special_dtypes.items()}
+ special_dtypes_size = {key: dtype_byte_size(dtyp) for key, dtyp in special_dtypes.items()}
+ module_sizes = defaultdict(int)
+
+ module_list = []
+
+ if not buffers_only:
+ module_list = named_module_tensors(model, recurse=True)
+ else:
+ module_list = model.named_buffers(recurse=True)
+
+ for name, tensor in module_list:
+ if special_dtypes is not None and name in special_dtypes:
+ size = tensor.numel() * special_dtypes_size[name]
+ elif dtype is None:
+ size = tensor.numel() * dtype_byte_size(tensor.dtype)
+ elif str(tensor.dtype).startswith(("torch.uint", "torch.int", "torch.bool")):
+ # According to the code in set_module_tensor_to_device, these types won't be converted
+ # so use their original size here
+ size = tensor.numel() * dtype_byte_size(tensor.dtype)
+ else:
+ size = tensor.numel() * min(dtype_size, dtype_byte_size(tensor.dtype))
+ name_parts = name.split(".")
+ for idx in range(len(name_parts) + 1):
+ module_sizes[".".join(name_parts[:idx])] += size
+
+ return module_sizes
+
+
+def compute_module_total_buffer_size(
+ model: nn.Module,
+ dtype: Optional[Union[str, torch.device]] = None,
+ special_dtypes: Optional[dict[str, Union[str, torch.device]]] = None,
+):
+ """
+ Compute the total size of buffers in each submodule of a given model.
+ """
+ module_sizes = compute_module_sizes(model, dtype=dtype, special_dtypes=special_dtypes, buffers_only=True)
+ return module_sizes.get("", 0)
+
+
+def get_max_layer_size(
+ modules: list[tuple[str, torch.nn.Module]], module_sizes: dict[str, int], no_split_module_classes: list[str]
+):
+ """
+ Utility function that will scan a list of named modules and return the maximum size used by one full layer. The
+ definition of a layer being:
+ - a module with no direct children (just parameters and buffers)
+ - a module whose class name is in the list `no_split_module_classes`
+
+ Args:
+ modules (`List[Tuple[str, torch.nn.Module]]`):
+ The list of named modules where we want to determine the maximum layer size.
+ module_sizes (`Dict[str, int]`):
+ A dictionary mapping each layer name to its size (as generated by `compute_module_sizes`).
+ no_split_module_classes (`List[str]`):
+ A list of class names for layers we don't want to be split.
+
+ Returns:
+ `Tuple[int, List[str]]`: The maximum size of a layer with the list of layer names realizing that maximum size.
+ """
+ max_size = 0
+ layer_names = []
+ modules_to_treat = modules.copy()
+ while len(modules_to_treat) > 0:
+ module_name, module = modules_to_treat.pop(0)
+ modules_children = list(module.named_children()) if isinstance(module, torch.nn.Module) else []
+ if len(modules_children) == 0 or module.__class__.__name__ in no_split_module_classes:
+ # No splitting this one so we compare to the max_size
+ size = module_sizes[module_name]
+ if size > max_size:
+ max_size = size
+ layer_names = [module_name]
+ elif size == max_size:
+ layer_names.append(module_name)
+ else:
+ modules_to_treat = [(f"{module_name}.{n}", v) for n, v in modules_children] + modules_to_treat
+ return max_size, layer_names
+
+
+def get_max_memory(max_memory: Optional[dict[Union[int, str], Union[int, str]]] = None):
+ """
+ Get the maximum memory available if nothing is passed, converts string to int otherwise.
+ """
+ import psutil
+
+ if max_memory is None:
+ max_memory = {}
+ # Make sure CUDA is initialized on each GPU to have the right memory info.
+ if is_npu_available():
+ for i in range(torch.npu.device_count()):
+ try:
+ _ = torch.tensor(0, device=torch.device("npu", i))
+ max_memory[i] = torch.npu.mem_get_info(i)[0]
+ except Exception:
+ logger.info(f"Device {i} seems unavailable, Proceeding to check subsequent devices.")
+ continue
+ elif is_mlu_available():
+ for i in range(torch.mlu.device_count()):
+ try:
+ _ = torch.tensor(0, device=torch.device("mlu", i))
+ max_memory[i] = torch.mlu.mem_get_info(i)[0]
+ except Exception:
+ logger.info(f"Device {i} seems unavailable, Proceeding to check subsequent devices.")
+ continue
+ elif is_sdaa_available():
+ for i in range(torch.sdaa.device_count()):
+ try:
+ _ = torch.tensor(0, device=torch.device("sdaa", i))
+ max_memory[i] = torch.sdaa.mem_get_info(i)[0]
+ except Exception:
+ logger.info(f"Device {i} seems unavailable, Proceeding to check subsequent devices.")
+ continue
+ elif is_musa_available():
+ for i in range(torch.musa.device_count()):
+ try:
+ _ = torch.tensor(0, device=torch.device("musa", i))
+ max_memory[i] = torch.musa.mem_get_info(i)[0]
+ except Exception:
+ logger.info(f"Device {i} seems unavailable, Proceeding to check subsequent devices.")
+ continue
+ elif is_xpu_available():
+ for i in range(torch.xpu.device_count()):
+ try:
+ _ = torch.tensor(0, device=torch.device("xpu", i))
+ max_memory[i] = get_xpu_available_memory(i)
+ except Exception:
+ logger.info(f"Device {i} seems unavailable, Proceeding to check subsequent devices.")
+ continue
+ elif is_hpu_available():
+ for i in range(torch.hpu.device_count()):
+ try:
+ _ = torch.tensor(0, device=torch.device("hpu", i))
+ max_memory[i] = torch.hpu.mem_get_info(i)[0]
+ except Exception:
+ logger.info(f"Device {i} seems unavailable, Proceeding to check subsequent devices.")
+ continue
+ else:
+ for i in range(torch.cuda.device_count()):
+ try:
+ _ = torch.tensor([0], device=i)
+ max_memory[i] = torch.cuda.mem_get_info(i)[0]
+ except Exception:
+ logger.info(f"Device {i} seems unavailable, Proceeding to check subsequent devices.")
+ continue
+ # allocate everything in the mps device as the RAM is shared
+ if is_mps_available():
+ max_memory["mps"] = psutil.virtual_memory().available
+ else:
+ max_memory["cpu"] = psutil.virtual_memory().available
+ return max_memory
+
+ for key in max_memory:
+ if isinstance(max_memory[key], str):
+ max_memory[key] = convert_file_size_to_int(max_memory[key])
+
+ # Need to sort the device by type to make sure that we allocate the gpu first.
+ # As gpu/npu/xpu are represented by int, we need to sort them first.
+ gpu_devices = [k for k in max_memory.keys() if isinstance(k, int)]
+ gpu_devices.sort()
+ # check if gpu/npu/xpu devices are available and if not, throw a warning
+ if is_npu_available():
+ num_devices = torch.npu.device_count()
+ elif is_mlu_available():
+ num_devices = torch.mlu.device_count()
+ elif is_sdaa_available():
+ num_devices = torch.sdaa.device_count()
+ elif is_musa_available():
+ num_devices = torch.musa.device_count()
+ elif is_xpu_available():
+ num_devices = torch.xpu.device_count()
+ elif is_hpu_available():
+ num_devices = torch.hpu.device_count()
+ else:
+ num_devices = torch.cuda.device_count()
+ for device in gpu_devices:
+ if device >= num_devices or device < 0:
+ logger.warning(f"Device {device} is not available, available devices are {list(range(num_devices))}")
+ # Add the other devices in the preset order if they are available
+ all_devices = gpu_devices + [k for k in ["mps", "cpu", "disk"] if k in max_memory.keys()]
+ # Raise an error if a device is not recognized
+ for k in max_memory.keys():
+ if k not in all_devices:
+ raise ValueError(
+ f"Device {k} is not recognized, available devices are integers(for GPU/XPU), 'mps', 'cpu' and 'disk'"
+ )
+ max_memory = {k: max_memory[k] for k in all_devices}
+
+ return max_memory
+
+
+def clean_device_map(device_map: dict[str, Union[int, str, torch.device]], module_name: str = ""):
+ """
+ Cleans a device_map by grouping all submodules that go on the same device together.
+ """
+ # Get the value of the current module and if there is only one split across several keys, regroup it.
+ prefix = "" if module_name == "" else f"{module_name}."
+ values = [v for k, v in device_map.items() if k.startswith(prefix)]
+ if len(set(values)) == 1 and len(values) > 1:
+ for k in [k for k in device_map if k.startswith(prefix)]:
+ del device_map[k]
+ device_map[module_name] = values[0]
+
+ # Recurse over the children
+ children_modules = [k for k in device_map.keys() if k.startswith(prefix) and len(k) > len(module_name)]
+ idx = len(module_name.split(".")) + 1 if len(module_name) > 0 else 1
+ children_modules = set(".".join(k.split(".")[:idx]) for k in children_modules)
+ for child in children_modules:
+ clean_device_map(device_map, module_name=child)
+
+ return device_map
+
+
+def load_offloaded_weights(model, index, offload_folder):
+ """
+ Loads the weights from the offload folder into the model.
+
+ Args:
+ model (`torch.nn.Module`):
+ The model to load the weights into.
+ index (`dict`):
+ A dictionary containing the parameter name and its metadata for each parameter that was offloaded from the
+ model.
+ offload_folder (`str`):
+ The folder where the offloaded weights are stored.
+ """
+ if index is None or len(index) == 0:
+ # Nothing to do
+ return
+ for param_name, metadata in index.items():
+ if "SCB" in param_name:
+ continue
+ fp16_statistics = None
+ if "weight" in param_name and param_name.replace("weight", "SCB") in index.keys():
+ weight_name = param_name.replace("weight", "SCB")
+ fp16_statistics = load_offloaded_weight(
+ os.path.join(offload_folder, f"{weight_name}.dat"), index[weight_name]
+ )
+ tensor_file = os.path.join(offload_folder, f"{param_name}.dat")
+ weight = load_offloaded_weight(tensor_file, metadata)
+ set_module_tensor_to_device(model, param_name, "cpu", value=weight, fp16_statistics=fp16_statistics)
+
+
+def get_module_leaves(module_sizes):
+ module_children = {}
+ for module in module_sizes:
+ if module == "" or "." not in module:
+ continue
+ parent = module.rsplit(".", 1)[0]
+ module_children[parent] = module_children.get(parent, 0) + 1
+ leaves = [module for module in module_sizes if module_children.get(module, 0) == 0 and module != ""]
+ return leaves
+
+
+def get_balanced_memory(
+ model: nn.Module,
+ max_memory: Optional[dict[Union[int, str], Union[int, str]]] = None,
+ no_split_module_classes: Optional[list[str]] = None,
+ dtype: Optional[Union[str, torch.dtype]] = None,
+ special_dtypes: Optional[dict[str, Union[str, torch.device]]] = None,
+ low_zero: bool = False,
+):
+ """
+ Compute a `max_memory` dictionary for [`infer_auto_device_map`] that will balance the use of each available GPU.
+
+
+
+ All computation is done analyzing sizes and dtypes of the model parameters. As a result, the model can be on the
+ meta device (as it would if initialized within the `init_empty_weights` context manager).
+
+
+
+ Args:
+ model (`torch.nn.Module`):
+ The model to analyze.
+ max_memory (`Dict`, *optional*):
+ A dictionary device identifier to maximum memory. Will default to the maximum memory available if unset.
+ Example: `max_memory={0: "1GB"}`.
+ no_split_module_classes (`List[str]`, *optional*):
+ A list of layer class names that should never be split across device (for instance any layer that has a
+ residual connection).
+ dtype (`str` or `torch.dtype`, *optional*):
+ If provided, the weights will be converted to that type when loaded.
+ special_dtypes (`Dict[str, Union[str, torch.device]]`, *optional*):
+ If provided, special dtypes to consider for some specific weights (will override dtype used as default for
+ all weights).
+ low_zero (`bool`, *optional*):
+ Minimizes the number of weights on GPU 0, which is convenient when it's used for other operations (like the
+ Transformers generate function).
+ """
+ # Get default / clean up max_memory
+ user_not_set_max_memory = max_memory is None
+ max_memory = get_max_memory(max_memory)
+
+ if is_npu_available():
+ expected_device_type = "npu"
+ elif is_mlu_available():
+ expected_device_type = "mlu"
+ elif is_sdaa_available():
+ expected_device_type = "sdaa"
+ elif is_musa_available():
+ expected_device_type = "musa"
+ elif is_xpu_available():
+ expected_device_type = "xpu"
+ elif is_hpu_available():
+ expected_device_type = "hpu"
+ elif is_mps_available():
+ expected_device_type = "mps"
+ else:
+ expected_device_type = "cuda"
+ num_devices = len([d for d in max_memory if torch.device(d).type == expected_device_type and max_memory[d] > 0])
+
+ if num_devices == 0:
+ return max_memory
+
+ if num_devices == 1:
+ # We cannot do low_zero on just one GPU, but we will still reserve some memory for the buffer
+ low_zero = False
+ # If user just asked us to handle memory usage, we should avoid OOM
+ if user_not_set_max_memory:
+ for key in max_memory.keys():
+ if isinstance(key, int):
+ max_memory[key] *= 0.9 # 90% is a good compromise
+ logger.info(
+ f"We will use 90% of the memory on device {key} for storing the model, and 10% for the buffer to avoid OOM. "
+ "You can set `max_memory` in to a higher value to use more memory (at your own risk)."
+ )
+ break # only one device
+
+ module_sizes = compute_module_sizes(model, dtype=dtype, special_dtypes=special_dtypes)
+ per_gpu = module_sizes[""] // (num_devices - 1 if low_zero else num_devices)
+
+ # We can't just set the memory to model_size // num_devices as it will end being too small: each GPU will get
+ # slightly less layers and some layers will end up offload at the end. So this function computes a buffer size to
+ # add which is the biggest of:
+ # - the size of no split block (if applicable)
+ # - the mean of the layer sizes
+ if no_split_module_classes is None:
+ no_split_module_classes = []
+ elif not isinstance(no_split_module_classes, (list, tuple)):
+ no_split_module_classes = [no_split_module_classes]
+
+ # Identify the size of the no_split_block modules
+ if len(no_split_module_classes) > 0:
+ no_split_children = {}
+ for name, size in module_sizes.items():
+ if name == "":
+ continue
+ submodule = model
+ for submodule_name in name.split("."):
+ submodule = getattr(submodule, submodule_name)
+ class_name = submodule.__class__.__name__
+ if class_name in no_split_module_classes and class_name not in no_split_children:
+ no_split_children[class_name] = size
+
+ if set(no_split_children.keys()) == set(no_split_module_classes):
+ break
+ buffer = max(no_split_children.values()) if len(no_split_children) > 0 else 0
+ else:
+ buffer = 0
+
+ # Compute mean of final modules. In the first dict of module sizes, leaves are the parameters
+ leaves = get_module_leaves(module_sizes)
+ leaves_set = set(leaves) # Convert to set for O(1) membership testing
+ module_sizes = {n: v for n, v in module_sizes.items() if n not in leaves_set}
+ # Once removed, leaves are the final modules.
+ leaves = get_module_leaves(module_sizes)
+ mean_leaves = int(sum([module_sizes[n] for n in leaves]) / max(len(leaves), 1))
+ buffer = int(1.25 * max(buffer, mean_leaves))
+ per_gpu += buffer
+
+ # Sorted list of GPUs id (we may have some gpu ids not included in the our max_memory list - let's ignore them)
+ gpus_idx_list = list(
+ sorted(
+ device_id for device_id, device_mem in max_memory.items() if isinstance(device_id, int) and device_mem > 0
+ )
+ )
+ # The last device is left with max_memory just in case the buffer is not enough.
+ for idx in gpus_idx_list[:-1]:
+ max_memory[idx] = min(max_memory[0] if low_zero and idx == 0 else per_gpu, max_memory[idx])
+
+ if low_zero:
+ min_zero = max(0, module_sizes[""] - sum([max_memory[i] for i in range(1, num_devices)]))
+ max_memory[0] = min(min_zero, max_memory[0])
+
+ return max_memory
+
+
+def calculate_maximum_sizes(model: torch.nn.Module):
+ "Computes the total size of the model and its largest layer"
+ sizes = compute_module_sizes(model)
+ # `transformers` models store this information for us
+ no_split_modules = getattr(model, "_no_split_modules", None)
+ if no_split_modules is None:
+ no_split_modules = []
+
+ modules_to_treat = (
+ list(model.named_parameters(recurse=False))
+ + list(model.named_children())
+ + list(model.named_buffers(recurse=False))
+ )
+ largest_layer = get_max_layer_size(modules_to_treat, sizes, no_split_modules)
+ total_size = sizes[""]
+ return total_size, largest_layer
+
+
+def _init_infer_auto_device_map(
+ model: nn.Module,
+ max_memory: Optional[dict[Union[int, str], Union[int, str]]] = None,
+ no_split_module_classes: Optional[list[str]] = None,
+ dtype: Optional[Union[str, torch.dtype]] = None,
+ special_dtypes: Optional[dict[str, Union[str, torch.device]]] = None,
+) -> tuple[
+ list[Union[int, str]],
+ dict[Union[int, str], Union[int, str]],
+ list[Union[int, str]],
+ list[int],
+ dict[str, int],
+ list[list[str]],
+ list[str],
+ list[tuple[str, nn.Module]],
+]:
+ """
+ Initialize variables required for computing the device map for model allocation.
+ """
+ max_memory = get_max_memory(max_memory)
+ if no_split_module_classes is None:
+ no_split_module_classes = []
+ elif not isinstance(no_split_module_classes, (list, tuple)):
+ no_split_module_classes = [no_split_module_classes]
+
+ devices = list(max_memory.keys())
+ if "disk" not in devices:
+ devices.append("disk")
+ gpus = [device for device in devices if device not in ["cpu", "disk"]]
+
+ # Devices that need to keep space for a potential offloaded layer.
+ if "mps" in gpus:
+ main_devices = ["mps"]
+ elif len(gpus) > 0:
+ main_devices = [gpus[0], "cpu"]
+ else:
+ main_devices = ["cpu"]
+
+ module_sizes = compute_module_sizes(model, dtype=dtype, special_dtypes=special_dtypes)
+ tied_parameters = find_tied_parameters(model)
+ if check_tied_parameters_in_config(model) and len(tied_parameters) == 0:
+ logger.warning(
+ "The model weights are not tied. Please use the `tie_weights` method before using the `infer_auto_device` function."
+ )
+
+ # Direct submodules and parameters
+ modules_to_treat = (
+ list(model.named_parameters(recurse=False))
+ + list(model.named_children())
+ + list(model.named_buffers(recurse=False))
+ )
+
+ return (
+ devices,
+ max_memory,
+ main_devices,
+ gpus,
+ module_sizes,
+ tied_parameters,
+ no_split_module_classes,
+ modules_to_treat,
+ )
+
+
+def get_module_size_with_ties(
+ tied_params,
+ module_size,
+ module_sizes,
+ modules_to_treat,
+) -> tuple[int, list[str], list[nn.Module]]:
+ """
+ Calculate the total size of a module, including its tied parameters.
+
+ Args:
+ tied_params (`List[str]`): The list of tied parameters.
+ module_size (`int`): The size of the module without tied parameters.
+ module_sizes (`Dict[str, int]`): A dictionary mapping each layer name to its size.
+ modules_to_treat (`List[Tuple[str, nn.Module]]`): The list of named modules to treat.
+
+ Returns:
+ `Tuple[int, List[str], List[nn.Module]]`: The total size of the module, the names of the tied modules, and the
+ tied modules.
+ """
+ if len(tied_params) < 1:
+ return module_size, [], []
+ tied_module_names = []
+ tied_modules = []
+
+ for tied_param in tied_params:
+ tied_module_index = [i for i, (n, _) in enumerate(modules_to_treat) if tied_param.startswith(n + ".")][0]
+ tied_module_names.append(modules_to_treat[tied_module_index][0])
+ tied_modules.append(modules_to_treat[tied_module_index][1])
+
+ module_size_with_ties = module_size
+ for tied_param, tied_module_name in zip(tied_params, tied_module_names):
+ module_size_with_ties += module_sizes[tied_module_name] - module_sizes[tied_param]
+
+ return module_size_with_ties, tied_module_names, tied_modules
+
+
+def fallback_allocate(
+ modules: list[tuple[str, nn.Module]],
+ module_sizes: dict[str, int],
+ size_limit: Union[int, str],
+ no_split_module_classes: Optional[list[str]] = None,
+ tied_parameters: Optional[list[list[str]]] = None,
+) -> tuple[Optional[str], Optional[nn.Module], list[tuple[str, nn.Module]]]:
+ """
+ Find a module that fits in the size limit using BFS and return it with its name and the remaining modules.
+
+ Args:
+ modules (`List[Tuple[str, nn.Module]]`):
+ The list of named modules to search in.
+ module_sizes (`Dict[str, int]`):
+ A dictionary mapping each layer name to its size (as generated by `compute_module_sizes`).
+ size_limit (`Union[int, str]`):
+ The maximum size a module can have.
+ no_split_module_classes (`Optional[List[str]]`, *optional*):
+ A list of class names for layers we don't want to be split.
+ tied_parameters (`Optional[List[List[str]]`, *optional*):
+ A list of lists of parameter names being all tied together.
+
+ Returns:
+ `Tuple[Optional[str], Optional[nn.Module], List[Tuple[str, nn.Module]]]`: A tuple containing:
+ - The name of the module that fits within the size limit.
+ - The module itself.
+ - The list of remaining modules after the found module is removed.
+ """
+ try:
+ size_limit = convert_file_size_to_int(size_limit)
+ except ValueError:
+ return None, None, modules
+
+ if no_split_module_classes is None:
+ no_split_module_classes = []
+
+ if tied_parameters is None:
+ tied_parameters = []
+
+ modules_to_search = modules.copy()
+ module_found = False
+
+ while modules_to_search:
+ name, module = modules_to_search.pop(0)
+
+ tied_param_groups = [
+ tied_group
+ for tied_group in tied_parameters
+ if any(name + "." in k + "." for k in tied_group) and not all(name + "." in k + "." for k in tied_group)
+ ]
+
+ tied_params = sum(
+ [[p for p in tied_group if name + "." not in p + "."] for tied_group in tied_param_groups], []
+ )
+
+ module_size_with_ties, _, _ = get_module_size_with_ties(
+ tied_params, module_sizes[name], module_sizes, modules_to_search
+ )
+
+ # If the module fits in the size limit, we found it.
+ if module_size_with_ties <= size_limit:
+ module_found = True
+ break
+
+ # The module is too big, we need to split it if possible.
+ modules_children = (
+ []
+ if isinstance(module, nn.Parameter) or isinstance(module, torch.Tensor)
+ else list(module.named_children())
+ )
+
+ # Split fails, move to the next module
+ if len(modules_children) == 0 or module.__class__.__name__ in no_split_module_classes:
+ continue
+
+ # split is possible, add the children to the list of modules to search
+ modules_children = list(module.named_parameters(recurse=False)) + modules_children
+ modules_to_search = [(f"{name}.{n}", v) for n, v in modules_children] + modules_to_search
+
+ if not module_found:
+ return None, None, modules
+
+ # Prepare the module list for removal of the found module
+ current_names = [n for n, _ in modules]
+ dot_idx = [i for i, c in enumerate(name) if c == "."]
+
+ for dot_index in dot_idx:
+ parent_name = name[:dot_index]
+ if parent_name in current_names:
+ parent_module_idx = current_names.index(parent_name)
+ _, parent_module = modules[parent_module_idx]
+ module_children = list(parent_module.named_parameters(recurse=False)) + list(
+ parent_module.named_children()
+ )
+ modules = (
+ modules[:parent_module_idx]
+ + [(f"{parent_name}.{n}", v) for n, v in module_children]
+ + modules[parent_module_idx + 1 :]
+ )
+ current_names = [n for n, _ in modules]
+
+ # Now the target module should be directly in the list
+ target_idx = current_names.index(name)
+ name, module = modules.pop(target_idx)
+
+ return name, module, modules
+
+
+def infer_auto_device_map(
+ model: nn.Module,
+ max_memory: Optional[dict[Union[int, str], Union[int, str]]] = None,
+ no_split_module_classes: Optional[list[str]] = None,
+ dtype: Optional[Union[str, torch.dtype]] = None,
+ special_dtypes: Optional[dict[str, Union[str, torch.dtype]]] = None,
+ verbose: bool = False,
+ clean_result: bool = True,
+ offload_buffers: bool = False,
+ fallback_allocation: bool = False,
+):
+ """
+ Compute a device map for a given model giving priority to GPUs, then offload on CPU and finally offload to disk,
+ such that:
+ - we don't exceed the memory available of any of the GPU.
+ - if offload to the CPU is needed, there is always room left on GPU 0 to put back the layer offloaded on CPU that
+ has the largest size.
+ - if offload to the CPU is needed,we don't exceed the RAM available on the CPU.
+ - if offload to the disk is needed, there is always room left on the CPU to put back the layer offloaded on disk
+ that has the largest size.
+
+
+
+ All computation is done analyzing sizes and dtypes of the model parameters. As a result, the model can be on the
+ meta device (as it would if initialized within the `init_empty_weights` context manager).
+
+
+
+ Args:
+ model (`torch.nn.Module`):
+ The model to analyze.
+ max_memory (`Dict`, *optional*):
+ A dictionary device identifier to maximum memory. Will default to the maximum memory available if unset.
+ Example: `max_memory={0: "1GB"}`.
+ no_split_module_classes (`List[str]`, *optional*):
+ A list of layer class names that should never be split across device (for instance any layer that has a
+ residual connection).
+ dtype (`str` or `torch.dtype`, *optional*):
+ If provided, the weights will be converted to that type when loaded.
+ special_dtypes (`Dict[str, Union[str, torch.device]]`, *optional*):
+ If provided, special dtypes to consider for some specific weights (will override dtype used as default for
+ all weights).
+ verbose (`bool`, *optional*, defaults to `False`):
+ Whether or not to provide debugging statements as the function builds the device_map.
+ clean_result (`bool`, *optional*, defaults to `True`):
+ Clean the resulting device_map by grouping all submodules that go on the same device together.
+ offload_buffers (`bool`, *optional*, defaults to `False`):
+ In the layers that are offloaded on the CPU or the hard drive, whether or not to offload the buffers as
+ well as the parameters.
+ fallback_allocation (`bool`, *optional*, defaults to `False`):
+ When regular allocation fails, try to allocate a module that fits in the size limit using BFS.
+ """
+
+ # Initialize the variables
+ (
+ devices,
+ max_memory,
+ main_devices,
+ gpus,
+ module_sizes,
+ tied_parameters,
+ no_split_module_classes,
+ modules_to_treat,
+ ) = _init_infer_auto_device_map(model, max_memory, no_split_module_classes, dtype, special_dtypes)
+
+ device_map = OrderedDict()
+ current_device = 0
+ device_memory_used = {device: 0 for device in devices}
+ device_buffer_sizes = {}
+ device_minimum_assignment_memory = {}
+
+ # Initialize maximum largest layer, to know which space to keep in memory
+ max_layer_size, max_layer_names = get_max_layer_size(modules_to_treat, module_sizes, no_split_module_classes)
+
+ # Ready ? This is going to be a bit messy.
+ while len(modules_to_treat) > 0:
+ name, module = modules_to_treat.pop(0)
+ if verbose:
+ print(f"\nTreating module {name}.")
+ # Max size in the remaining layers may have changed since we took one, so we maybe update it.
+ max_layer_names = [n for n in max_layer_names if n != name and not n.startswith(name + ".")]
+ if len(max_layer_names) == 0:
+ max_layer_size, max_layer_names = get_max_layer_size(
+ [(n, m) for n, m in modules_to_treat if isinstance(m, torch.nn.Module)],
+ module_sizes,
+ no_split_module_classes,
+ )
+ # Assess size needed
+ module_size = module_sizes[name]
+
+ # We keep relevant tied parameters only: one of the tied parameters in the group is inside the current module
+ # and the other is not.
+ # Note: If we are currently processing the name `compute.weight`, an other parameter named
+ # e.g. `compute.weight_submodule.parameter`
+ # needs to be considered outside the current module, hence the check with additional dots.
+ tied_param_groups = [
+ tied_group
+ for tied_group in tied_parameters
+ if any(name + "." in k + "." for k in tied_group) and not all(name + "." in k + "." for k in tied_group)
+ ]
+
+ if verbose and len(tied_param_groups) > 0:
+ print(f" Found the relevant tied param groups {tied_param_groups}")
+
+ # Then we keep track of all the parameters that are tied to the current module, but not in the current module
+ tied_params = sum(
+ [[p for p in tied_group if name + "." not in p + "."] for tied_group in tied_param_groups], []
+ )
+
+ if verbose and len(tied_params) > 0:
+ print(f" So those parameters need to be taken into account {tied_params}")
+
+ device = devices[current_device]
+ current_max_size = max_memory[device] if device != "disk" else None
+ current_memory_reserved = 0
+ # Reduce max size available by the largest layer.
+ if devices[current_device] in main_devices:
+ current_max_size = current_max_size - max_layer_size
+ current_memory_reserved = max_layer_size
+
+ module_size_with_ties, tied_module_names, tied_modules = get_module_size_with_ties(
+ tied_params, module_size, module_sizes, modules_to_treat
+ )
+
+ # The module and its tied modules fit on the current device.
+ if current_max_size is None or device_memory_used[device] + module_size_with_ties <= current_max_size:
+ if verbose:
+ output = f"Putting {name}"
+
+ if tied_module_names:
+ output += f" and {tied_module_names}"
+ else:
+ output += f" (size={module_size})"
+
+ if current_max_size is not None:
+ output += f" (available={current_max_size - device_memory_used[device]})"
+
+ output += f" on {device}."
+ print(output)
+
+ device_memory_used[device] += module_size_with_ties
+
+ # Assign the primary module to the device.
+ device_map[name] = device
+
+ # Assign tied modules if any.
+ for tied_module_name in tied_module_names:
+ if tied_module_name in [m[0] for m in modules_to_treat]:
+ # Find the index of the tied module in the list
+ tied_module_index = next(i for i, (n, _) in enumerate(modules_to_treat) if n == tied_module_name)
+ # Remove the tied module from the list to prevent reprocessing
+ modules_to_treat.pop(tied_module_index)
+
+ # Assign the tied module to the device
+ device_map[tied_module_name] = device
+
+ # Buffer Handling
+ if not offload_buffers and isinstance(module, nn.Module):
+ # Compute the total buffer size for the module
+ current_buffer_size = compute_module_total_buffer_size(
+ module, dtype=dtype, special_dtypes=special_dtypes
+ )
+ # Update the buffer size on the device
+ device_buffer_sizes[device] = device_buffer_sizes.get(device, 0) + current_buffer_size
+
+ continue
+
+ # The current module itself fits, so we try to split the tied modules.
+ if len(tied_params) > 0 and device_memory_used[device] + module_size <= current_max_size:
+ # can we split one of the tied modules to make it smaller or do we need to go on the next device?
+ if verbose:
+ print(
+ f"Not enough space on {devices[current_device]} to put {name} and {tied_module_names} (space "
+ f"available {current_max_size - device_memory_used[device]}, needed size {module_size_with_ties})."
+ )
+ split_happened = False
+ for tied_module_name, tied_module in zip(tied_module_names, tied_modules):
+ tied_module_children = list(tied_module.named_children())
+ if len(tied_module_children) == 0 or tied_module.__class__.__name__ in no_split_module_classes:
+ # can't break this one.
+ continue
+
+ if verbose:
+ print(f"Splitting {tied_module_name}.")
+ tied_module_children = list(tied_module.named_parameters(recurse=False)) + tied_module_children
+ tied_module_children = [(f"{tied_module_name}.{n}", v) for n, v in tied_module_children]
+ tied_module_index = [i for i, (n, _) in enumerate(modules_to_treat) if n == tied_module_name][0]
+
+ modules_to_treat = (
+ [(name, module)]
+ + modules_to_treat[:tied_module_index]
+ + tied_module_children
+ + modules_to_treat[tied_module_index + 1 :]
+ )
+ # Update the max layer size.
+ max_layer_size, max_layer_names = get_max_layer_size(
+ [(n, m) for n, m in modules_to_treat if isinstance(m, torch.nn.Module)],
+ module_sizes,
+ no_split_module_classes,
+ )
+ split_happened = True
+ break
+
+ if split_happened:
+ continue
+
+ # If the tied module is not split, we go to the next device
+ if verbose:
+ print("None of the tied module can be split, going to the next device.")
+
+ # The current module itself doesn't fit, so we have to split it or go to the next device.
+ if device_memory_used[device] + module_size >= current_max_size:
+ # Split or not split?
+ modules_children = (
+ []
+ if isinstance(module, nn.Parameter) or isinstance(module, torch.Tensor)
+ else list(module.named_children())
+ )
+ if verbose:
+ print(
+ f"Not enough space on {devices[current_device]} to put {name} (space available "
+ f"{current_max_size - device_memory_used[device]}, module size {module_size})."
+ )
+ if len(modules_children) == 0 or module.__class__.__name__ in no_split_module_classes:
+ # -> no split, we go to the next device
+ if verbose:
+ print("This module cannot be split, going to the next device.")
+
+ else:
+ # -> split, we replace the module studied by its children + parameters
+ if verbose:
+ print(f"Splitting {name}.")
+ modules_children = list(module.named_parameters(recurse=False)) + modules_children
+ modules_to_treat = [(f"{name}.{n}", v) for n, v in modules_children] + modules_to_treat
+ # Update the max layer size.
+ max_layer_size, max_layer_names = get_max_layer_size(
+ [(n, m) for n, m in modules_to_treat if isinstance(m, torch.nn.Module)],
+ module_sizes,
+ no_split_module_classes,
+ )
+ continue
+
+ # If no module is assigned to the current device, we attempt to allocate a fallback module
+ # if fallback_allocation is enabled.
+ if device_memory_used[device] == 0 and fallback_allocation and device != "disk":
+ # We try to allocate a module that fits in the size limit using BFS.
+ # Recompute the current max size as we need to consider the current module as well.
+ current_max_size = max_memory[device] - max(max_layer_size, module_size_with_ties)
+
+ fallback_module_name, fallback_module, remaining_modules = fallback_allocate(
+ modules_to_treat,
+ module_sizes,
+ current_max_size - device_memory_used[device],
+ no_split_module_classes,
+ tied_parameters,
+ )
+ # use the next iteration to put the fallback module on the next device to avoid code duplication
+ if fallback_module is not None:
+ modules_to_treat = [(fallback_module_name, fallback_module)] + [(name, module)] + remaining_modules
+ continue
+
+ if device_memory_used[device] == 0:
+ device_minimum_assignment_memory[device] = module_size_with_ties + current_memory_reserved
+
+ # Neither the current module nor any tied modules can be split, so we move to the next device.
+ device_memory_used[device] = device_memory_used[device] + current_memory_reserved
+ current_device += 1
+ modules_to_treat = [(name, module)] + modules_to_treat
+
+ device_memory_used = {device: mem for device, mem in device_memory_used.items() if mem > 0}
+
+ if clean_result:
+ device_map = clean_device_map(device_map)
+
+ non_gpu_buffer_size = device_buffer_sizes.get("cpu", 0) + device_buffer_sizes.get("disk", 0)
+ if non_gpu_buffer_size > 0 and not offload_buffers:
+ is_buffer_fit_any_gpu = False
+ for gpu_device, gpu_max_memory in max_memory.items():
+ if gpu_device == "cpu" or gpu_device == "disk":
+ continue
+
+ if not is_buffer_fit_any_gpu:
+ gpu_memory_used = device_memory_used.get(gpu_device, 0)
+
+ if gpu_max_memory >= non_gpu_buffer_size + gpu_memory_used:
+ is_buffer_fit_any_gpu = True
+
+ if len(gpus) > 0 and not is_buffer_fit_any_gpu:
+ warnings.warn(
+ f"Current model requires {non_gpu_buffer_size} bytes of buffer for offloaded layers, which seems does "
+ f"not fit any GPU's remaining memory. If you are experiencing a OOM later, please consider using "
+ f"offload_buffers=True."
+ )
+
+ if device_minimum_assignment_memory:
+ devices_info = "\n".join(
+ f" - {device}: {mem} bytes required" for device, mem in device_minimum_assignment_memory.items()
+ )
+ logger.info(
+ f"Based on the current allocation process, no modules could be assigned to the following devices due to "
+ f"insufficient memory:\n"
+ f"{devices_info}\n"
+ f"These minimum requirements are specific to this allocation attempt and may vary. Consider increasing "
+ f"the available memory for these devices to at least the specified minimum, or adjusting the model config."
+ )
+ return device_map
+
+
+def check_device_map(model: nn.Module, device_map: dict[str, Union[int, str, torch.device]]):
+ """
+ Checks a device map covers everything in a given model.
+
+ Args:
+ model (`torch.nn.Module`): The model to check the device map against.
+ device_map (`Dict[str, Union[int, str, torch.device]]`): The device map to check.
+ """
+ all_module_names = dict(model.named_modules())
+ invalid_keys = [k for k in device_map if k != "" and k not in all_module_names]
+
+ if invalid_keys:
+ warnings.warn(
+ f"The following device_map keys do not match any submodules in the model: {invalid_keys}", UserWarning
+ )
+
+ all_model_tensors = [name for name, _ in model.state_dict().items()]
+ for module_name in device_map.keys():
+ if module_name == "":
+ all_model_tensors.clear()
+ break
+ else:
+ all_model_tensors = [
+ name
+ for name in all_model_tensors
+ if not name == module_name and not name.startswith(module_name + ".")
+ ]
+ if len(all_model_tensors) > 0:
+ non_covered_params = ", ".join(all_model_tensors)
+ raise ValueError(
+ f"The device_map provided does not give any device for the following parameters: {non_covered_params}"
+ )
+
+
+def load_state_dict(checkpoint_file, device_map=None):
+ """
+ Load a checkpoint from a given file. If the checkpoint is in the safetensors format and a device map is passed, the
+ weights can be fast-loaded directly on the GPU.
+
+ Args:
+ checkpoint_file (`str`): The path to the checkpoint to load.
+ device_map (`Dict[str, Union[int, str, torch.device]]`, *optional*):
+ A map that specifies where each submodule should go. It doesn't need to be refined to each parameter/buffer
+ name, once a given module name is inside, every submodule of it will be sent to the same device.
+ """
+ if checkpoint_file.endswith(".safetensors"):
+ with safe_open(checkpoint_file, framework="pt") as f:
+ metadata = f.metadata()
+ weight_names = f.keys()
+
+ if metadata is None:
+ logger.warning(
+ f"The safetensors archive passed at {checkpoint_file} does not contain metadata. "
+ "Make sure to save your model with the `save_pretrained` method. Defaulting to 'pt' metadata."
+ )
+ metadata = {"format": "pt"}
+
+ if metadata.get("format") not in ["pt", "tf", "flax"]:
+ raise OSError(
+ f"The safetensors archive passed at {checkpoint_file} does not contain the valid metadata. Make sure "
+ "you save your model with the `save_pretrained` method."
+ )
+ elif metadata["format"] != "pt":
+ raise ValueError(f"The checkpoint passed was saved with {metadata['format']}, we need a the pt format.")
+ if device_map is None:
+ return safe_load_file(checkpoint_file)
+ else:
+ # if we only have one device we can load everything directly
+ if len(set(device_map.values())) == 1:
+ device = list(device_map.values())[0]
+ target_device = device
+ if isinstance(device, int):
+ if is_npu_available():
+ target_device = f"npu:{device}"
+ elif is_hpu_available():
+ target_device = "hpu"
+
+ return safe_load_file(checkpoint_file, device=target_device)
+
+ devices = list(set(device_map.values()) - {"disk"})
+ # cpu device should always exist as fallback option
+ if "cpu" not in devices:
+ devices.append("cpu")
+
+ # For each device, get the weights that go there
+ device_weights = {device: [] for device in devices}
+ for module_name, device in device_map.items():
+ if device in devices:
+ device_weights[device].extend(
+ [k for k in weight_names if k == module_name or k.startswith(module_name + ".")]
+ )
+
+ # all weights that haven't defined a device should be loaded on CPU
+ device_weights["cpu"].extend([k for k in weight_names if k not in sum(device_weights.values(), [])])
+ tensors = {}
+ if is_tqdm_available():
+ progress_bar = tqdm(
+ main_process_only=False,
+ total=sum([len(device_weights[device]) for device in devices]),
+ unit="w",
+ smoothing=0,
+ leave=False,
+ )
+ else:
+ progress_bar = None
+ for device in devices:
+ target_device = device
+ if isinstance(device, int):
+ if is_npu_available():
+ target_device = f"npu:{device}"
+ elif is_hpu_available():
+ target_device = "hpu"
+
+ with safe_open(checkpoint_file, framework="pt", device=target_device) as f:
+ for key in device_weights[device]:
+ if progress_bar is not None:
+ progress_bar.set_postfix(dev=device, refresh=False)
+ progress_bar.set_description(key)
+ tensors[key] = f.get_tensor(key)
+ if progress_bar is not None:
+ progress_bar.update()
+ if progress_bar is not None:
+ progress_bar.close()
+
+ return tensors
+ else:
+ return torch.load(checkpoint_file, map_location=torch.device("cpu"), weights_only=True)
+
+
+def get_state_dict_offloaded_model(model: nn.Module):
+ """
+ Returns the state dictionary for an offloaded model via iterative onloading
+
+ Args:
+ model (`torch.nn.Module`):
+ The offloaded model we want to save
+ """
+
+ state_dict = {}
+ placeholders = set()
+ for name, module in model.named_modules():
+ if name == "":
+ continue
+
+ try:
+ with align_module_device(module, "cpu"):
+ module_state_dict = module.state_dict()
+ except MemoryError:
+ raise MemoryError("Offloaded module must fit in CPU memory to call save_model!") from None
+
+ for key in module_state_dict:
+ # ignore placeholder parameters that are still on the meta device
+ if module_state_dict[key].device == torch.device("meta"):
+ placeholders.add(name + f".{key}")
+ continue
+ params = module_state_dict[key]
+ state_dict[name + f".{key}"] = params.to("cpu") # move buffers to cpu
+ for key in placeholders.copy():
+ if key in state_dict:
+ placeholders.remove(key)
+ if placeholders:
+ logger.warning(f"The following tensors were not saved because they were still on meta device: {placeholders}")
+
+ return state_dict
+
+
+def get_state_dict_from_offload(
+ module: nn.Module,
+ module_name: str,
+ state_dict: dict[str, Union[str, torch.tensor]],
+ device_to_put_offload: Union[int, str, torch.device] = "cpu",
+):
+ """
+ Retrieve the state dictionary (with parameters) from an offloaded module and load into a specified device (defaults
+ to cpu).
+
+ Args:
+ module: (`torch.nn.Module`):
+ The module we want to retrieve a state dictionary from
+ module_name: (`str`):
+ The name of the module of interest
+ state_dict (`Dict[str, Union[int, str, torch.device]]`):
+ Dictionary of {module names: parameters}
+ device_to_put_offload (`Union[int, str, torch.device]`):
+ Device to load offloaded parameters into, defaults to the cpu.
+ """
+
+ root = module_name[: module_name.rfind(".")] # module name without .weight or .bias
+
+ # do not move parameters if the module is not offloaded
+ if not has_offloaded_params(module):
+ device_to_put_offload = None
+
+ # assign the device to which the offloaded parameters will be sent
+ with align_module_device(module, device_to_put_offload):
+ for m_key, params in module.state_dict().items():
+ if (root + f".{m_key}") in state_dict:
+ state_dict[root + f".{m_key}"] = params
+
+ return state_dict
+
+
+def load_checkpoint_in_model(
+ model: nn.Module,
+ checkpoint: Union[str, os.PathLike],
+ device_map: Optional[dict[str, Union[int, str, torch.device]]] = None,
+ offload_folder: Optional[Union[str, os.PathLike]] = None,
+ dtype: Optional[Union[str, torch.dtype]] = None,
+ offload_state_dict: bool = False,
+ offload_buffers: bool = False,
+ keep_in_fp32_modules: Optional[list[str]] = None,
+ offload_8bit_bnb: bool = False,
+ strict: bool = False,
+ full_state_dict: bool = True,
+ broadcast_from_rank0: bool = False,
+):
+ """
+ Loads a (potentially sharded) checkpoint inside a model, potentially sending weights to a given device as they are
+ loaded.
+
+
+
+ Once loaded across devices, you still need to call [`dispatch_model`] on your model to make it able to run. To
+ group the checkpoint loading and dispatch in one single call, use [`load_checkpoint_and_dispatch`].
+
+
+
+ Args:
+ model (`torch.nn.Module`):
+ The model in which we want to load a checkpoint.
+ checkpoint (`str` or `os.PathLike`):
+ The folder checkpoint to load. It can be:
+ - a path to a file containing a whole model state dict
+ - a path to a `.json` file containing the index to a sharded checkpoint
+ - a path to a folder containing a unique `.index.json` file and the shards of a checkpoint.
+ - a path to a folder containing a unique pytorch_model.bin or a model.safetensors file.
+ device_map (`Dict[str, Union[int, str, torch.device]]`, *optional*):
+ A map that specifies where each submodule should go. It doesn't need to be refined to each parameter/buffer
+ name, once a given module name is inside, every submodule of it will be sent to the same device.
+ offload_folder (`str` or `os.PathLike`, *optional*):
+ If the `device_map` contains any value `"disk"`, the folder where we will offload weights.
+ dtype (`str` or `torch.dtype`, *optional*):
+ If provided, the weights will be converted to that type when loaded.
+ offload_state_dict (`bool`, *optional*, defaults to `False`):
+ If `True`, will temporarily offload the CPU state dict on the hard drive to avoid getting out of CPU RAM if
+ the weight of the CPU state dict + the biggest shard does not fit.
+ offload_buffers (`bool`, *optional*, defaults to `False`):
+ Whether or not to include the buffers in the weights offloaded to disk.
+ keep_in_fp32_modules(`List[str]`, *optional*):
+ A list of the modules that we keep in `torch.float32` dtype.
+ offload_8bit_bnb (`bool`, *optional*):
+ Whether or not to enable offload of 8-bit modules on cpu/disk.
+ strict (`bool`, *optional*, defaults to `False`):
+ Whether to strictly enforce that the keys in the checkpoint state_dict match the keys of the model's
+ state_dict.
+ full_state_dict (`bool`, *optional*, defaults to `True`): if this is set to `True`, all the tensors in the
+ loaded state_dict will be gathered. No ShardedTensor and DTensor will be in the loaded state_dict.
+ broadcast_from_rank0 (`False`, *optional*, defaults to `False`): when the option is `True`, a distributed
+ `ProcessGroup` must be initialized. rank0 should receive a full state_dict and will broadcast the tensors
+ in the state_dict one by one to other ranks. Other ranks will receive the tensors and shard (if applicable)
+ according to the local shards in the model.
+
+ """
+ if offload_8bit_bnb:
+ from .bnb import quantize_and_offload_8bit
+
+ tied_params = find_tied_parameters(model)
+
+ if check_tied_parameters_in_config(model) and len(tied_params) == 0:
+ logger.warning(
+ "The model weights are not tied. Please use the `tie_weights` method before using the `infer_auto_device` function."
+ )
+ if device_map is not None:
+ check_tied_parameters_on_same_device(tied_params, device_map)
+
+ if offload_folder is None and device_map is not None and "disk" in device_map.values():
+ raise ValueError(
+ "At least one of the model submodule will be offloaded to disk, please pass along an `offload_folder`."
+ )
+ elif offload_folder is not None and device_map is not None and "disk" in device_map.values():
+ os.makedirs(offload_folder, exist_ok=True)
+
+ if isinstance(dtype, str):
+ # We accept "torch.float16" or just "float16"
+ dtype = dtype.replace("torch.", "")
+ dtype = getattr(torch, dtype)
+
+ checkpoint_files = None
+ index_filename = None
+ if os.path.isfile(checkpoint):
+ if str(checkpoint).endswith(".json"):
+ index_filename = checkpoint
+ else:
+ checkpoint_files = [checkpoint]
+ elif os.path.isdir(checkpoint):
+ # check if the whole state dict is present
+ potential_state_bin = [f for f in os.listdir(checkpoint) if f == WEIGHTS_NAME]
+ potential_state_safetensor = [f for f in os.listdir(checkpoint) if f == SAFE_WEIGHTS_NAME]
+ if len(potential_state_bin) == 1:
+ checkpoint_files = [os.path.join(checkpoint, potential_state_bin[0])]
+ elif len(potential_state_safetensor) == 1:
+ checkpoint_files = [os.path.join(checkpoint, potential_state_safetensor[0])]
+ else:
+ # otherwise check for sharded checkpoints
+ potential_index = [f for f in os.listdir(checkpoint) if f.endswith(".index.json")]
+ if len(potential_index) == 0:
+ raise ValueError(
+ f"{checkpoint} is not a folder containing a `.index.json` file or a {WEIGHTS_NAME} or a {SAFE_WEIGHTS_NAME} file"
+ )
+ elif len(potential_index) == 1:
+ index_filename = os.path.join(checkpoint, potential_index[0])
+ else:
+ raise ValueError(
+ f"{checkpoint} containing more than one `.index.json` file, delete the irrelevant ones."
+ )
+ else:
+ raise ValueError(
+ "`checkpoint` should be the path to a file containing a whole state dict, or the index of a sharded "
+ f"checkpoint, or a folder containing a sharded checkpoint or the whole state dict, but got {checkpoint}."
+ )
+
+ if index_filename is not None:
+ checkpoint_folder = os.path.split(index_filename)[0]
+ with open(index_filename) as f:
+ index = json.loads(f.read())
+
+ if "weight_map" in index:
+ index = index["weight_map"]
+ checkpoint_files = sorted(list(set(index.values())))
+ checkpoint_files = [os.path.join(checkpoint_folder, f) for f in checkpoint_files]
+
+ # Logic for missing/unexepected keys goes here.
+
+ offload_index = {}
+ if offload_state_dict:
+ state_dict_folder = tempfile.mkdtemp()
+ state_dict_index = {}
+
+ unexpected_keys = set()
+ model_keys = set(model.state_dict().keys())
+ buffer_names = [name for name, _ in model.named_buffers()]
+ model_devices = {t.device for t in model.state_dict().values() if isinstance(t, torch.Tensor)}
+ model_physical_devices = model_devices - {torch.device("meta")}
+ for checkpoint_file in checkpoint_files:
+ if device_map is None:
+ # exception for multi-device loading was made for the meta device in torch v2.7.0
+ # https://github.com/pytorch/pytorch/blob/v2.6.0/torch/distributed/checkpoint/state_dict.py#L557-L563
+ # https://github.com/pytorch/pytorch/blob/v2.7.0-rc2/torch/distributed/checkpoint/state_dict.py#L575-L587
+ if is_torch_version(">=", "2.2.0") and (
+ (is_torch_version(">=", "2.7.0") and len(model_physical_devices) <= 1) or len(model_devices) <= 1
+ ):
+ from torch.distributed.checkpoint.state_dict import StateDictOptions, set_model_state_dict
+
+ broadcast_from_rank0 &= is_torch_version(">=", "2.4.0")
+ loaded_checkpoint = (
+ load_state_dict(checkpoint_file, device_map=device_map)
+ if not broadcast_from_rank0 or dist.get_rank() == 0
+ else {}
+ )
+ set_model_state_dict(
+ model,
+ loaded_checkpoint,
+ options=StateDictOptions(
+ full_state_dict=full_state_dict,
+ strict=strict,
+ **({"broadcast_from_rank0": broadcast_from_rank0} if is_torch_version(">=", "2.4.0") else {}),
+ ),
+ )
+ else:
+ loaded_checkpoint = load_state_dict(checkpoint_file, device_map=device_map)
+ model.load_state_dict(loaded_checkpoint, strict=strict)
+
+ unexpected_keys.update(set(loaded_checkpoint.keys()) - model_keys)
+ else:
+ loaded_checkpoint = load_state_dict(checkpoint_file, device_map=device_map)
+
+ for param_name, param in loaded_checkpoint.items():
+ # skip SCB parameter (for 8-bit serialization)
+ if "SCB" in param_name:
+ continue
+
+ if param_name not in model_keys:
+ unexpected_keys.add(param_name)
+ if not strict:
+ continue # Skip loading this parameter.
+
+ module_name = param_name
+
+ while len(module_name) > 0 and module_name not in device_map:
+ module_name = ".".join(module_name.split(".")[:-1])
+ if module_name == "" and "" not in device_map:
+ # TODO: group all errors and raise at the end.
+ raise ValueError(f"{param_name} doesn't have any device set.")
+ param_device = device_map[module_name]
+ new_dtype = dtype
+ if dtype is not None and torch.is_floating_point(param):
+ if keep_in_fp32_modules is not None and dtype == torch.float16:
+ proceed = False
+ for key in keep_in_fp32_modules:
+ if ((key in param_name) and (key + "." in param_name)) or key == param_name:
+ proceed = True
+ break
+ if proceed:
+ new_dtype = torch.float32
+
+ if "weight" in param_name and param_name.replace("weight", "SCB") in loaded_checkpoint.keys():
+ if param.dtype == torch.int8:
+ fp16_statistics = loaded_checkpoint[param_name.replace("weight", "SCB")]
+ else:
+ fp16_statistics = None
+
+ if param_device == "disk":
+ if offload_buffers or param_name not in buffer_names:
+ if new_dtype is None:
+ new_dtype = param.dtype
+ if offload_8bit_bnb:
+ quantize_and_offload_8bit(
+ model, param, param_name, new_dtype, offload_folder, offload_index, fp16_statistics
+ )
+ continue
+ else:
+ set_module_tensor_to_device(model, param_name, "meta", dtype=new_dtype)
+ offload_weight(param, param_name, offload_folder, index=offload_index)
+ elif param_device == "cpu" and offload_state_dict:
+ if new_dtype is None:
+ new_dtype = param.dtype
+ if offload_8bit_bnb:
+ quantize_and_offload_8bit(
+ model, param, param_name, new_dtype, state_dict_folder, state_dict_index, fp16_statistics
+ )
+ else:
+ set_module_tensor_to_device(model, param_name, "meta", dtype=new_dtype)
+ offload_weight(param, param_name, state_dict_folder, index=state_dict_index)
+ else:
+ set_module_tensor_to_device(
+ model,
+ param_name,
+ param_device,
+ value=param,
+ dtype=new_dtype,
+ fp16_statistics=fp16_statistics,
+ )
+
+ # Force Python to clean up.
+ del loaded_checkpoint
+ gc.collect()
+
+ if not strict and len(unexpected_keys) > 0:
+ logger.warning(
+ f"Some weights of the model checkpoint at {checkpoint} were not used when"
+ f" initializing {model.__class__.__name__}: {unexpected_keys}. This may or may not be an issue - make sure that the checkpoint does not have unnecessary parameters, or that the model definition correctly corresponds to the checkpoint."
+ )
+
+ save_offload_index(offload_index, offload_folder)
+
+ # Load back offloaded state dict on CPU
+ if offload_state_dict:
+ load_offloaded_weights(model, state_dict_index, state_dict_folder)
+ shutil.rmtree(state_dict_folder)
+
+ retie_parameters(model, tied_params)
+
+
+def get_mixed_precision_context_manager(native_amp: bool = False, autocast_kwargs: AutocastKwargs = None):
+ """
+ Return a context manager for autocasting mixed precision
+
+ Args:
+ native_amp (`bool`, *optional*, defaults to False):
+ Whether mixed precision is actually enabled.
+ cache_enabled (`bool`, *optional*, defaults to True):
+ Whether the weight cache inside autocast should be enabled.
+ """
+ state = AcceleratorState()
+ if autocast_kwargs is None:
+ autocast_kwargs = {}
+ else:
+ autocast_kwargs = autocast_kwargs.to_kwargs()
+ if native_amp:
+ device_type = (
+ "cuda"
+ if (state.distributed_type == DistributedType.XLA and is_torch_xla_available(check_is_gpu=True))
+ else state.device.type
+ )
+ if state.mixed_precision == "fp16":
+ return torch.autocast(device_type=device_type, dtype=torch.float16, **autocast_kwargs)
+ elif state.mixed_precision in ["bf16", "fp8"] and state.distributed_type in [
+ DistributedType.NO,
+ DistributedType.MULTI_CPU,
+ DistributedType.MULTI_GPU,
+ DistributedType.MULTI_MLU,
+ DistributedType.MULTI_SDAA,
+ DistributedType.MULTI_MUSA,
+ DistributedType.MULTI_NPU,
+ DistributedType.MULTI_XPU,
+ DistributedType.MULTI_HPU,
+ DistributedType.FSDP,
+ DistributedType.XLA,
+ ]:
+ return torch.autocast(device_type=device_type, dtype=torch.bfloat16, **autocast_kwargs)
+ else:
+ return torch.autocast(device_type=device_type, **autocast_kwargs)
+ else:
+ return contextlib.nullcontext()
+
+
+def get_grad_scaler(distributed_type: DistributedType = None, **kwargs):
+ """
+ A generic helper which will initialize the correct `GradScaler` implementation based on the environment and return
+ it.
+
+ Args:
+ distributed_type (`DistributedType`, *optional*, defaults to None):
+ The type of distributed environment.
+ kwargs:
+ Additional arguments for the utilized `GradScaler` constructor.
+ """
+ if distributed_type == DistributedType.FSDP:
+ from torch.distributed.fsdp.sharded_grad_scaler import ShardedGradScaler
+
+ return ShardedGradScaler(**kwargs)
+ if is_torch_xla_available(check_is_gpu=True):
+ import torch_xla.amp as xamp
+
+ return xamp.GradScaler(**kwargs)
+ elif is_mlu_available():
+ return torch.mlu.amp.GradScaler(**kwargs)
+ elif is_sdaa_available():
+ return torch.sdaa.amp.GradScaler(**kwargs)
+ elif is_musa_available():
+ return torch.musa.amp.GradScaler(**kwargs)
+ elif is_npu_available():
+ return torch.npu.amp.GradScaler(**kwargs)
+ elif is_hpu_available():
+ return torch.amp.GradScaler("hpu", **kwargs)
+ elif is_xpu_available():
+ return torch.amp.GradScaler("xpu", **kwargs)
+ elif is_mps_available():
+ if not is_torch_version(">=", "2.8.0"):
+ raise ValueError("Grad Scaler with MPS device requires a Pytorch >= 2.8.0")
+ return torch.amp.GradScaler("mps", **kwargs)
+ else:
+ if is_torch_version(">=", "2.3"):
+ return torch.amp.GradScaler("cuda", **kwargs)
+ else:
+ return torch.cuda.amp.GradScaler(**kwargs)
+
+
+def has_offloaded_params(module: torch.nn.Module) -> bool:
+ """
+ Checks if a module has offloaded parameters by checking if the given module has a AlignDevicesHook attached with
+ offloading enabled
+
+ Args:
+ module (`torch.nn.Module`): The module to check for an offload hook.
+
+ Returns:
+ bool: `True` if the module has an offload hook and offloading is enabled, `False` otherwise.
+ """
+ from ..hooks import AlignDevicesHook # avoid circular import
+
+ return hasattr(module, "_hf_hook") and isinstance(module._hf_hook, AlignDevicesHook) and module._hf_hook.offload
+
+
+@contextlib.contextmanager
+def align_module_device(module: torch.nn.Module, execution_device: Optional[torch.device] = None):
+ """
+ Context manager that moves a module's parameters to the specified execution device.
+
+ Args:
+ module (`torch.nn.Module`):
+ Module with parameters to align.
+ execution_device (`torch.device`, *optional*):
+ If provided, overrides the module's execution device within the context. Otherwise, use hook execution
+ device or pass
+ """
+ if has_offloaded_params(module):
+ if execution_device is not None:
+ original_device = module._hf_hook.execution_device
+ module._hf_hook.execution_device = execution_device
+
+ try:
+ module._hf_hook.pre_forward(module)
+ yield
+ finally:
+ module._hf_hook.post_forward(module, None)
+ if execution_device is not None:
+ module._hf_hook.execution_device = original_device
+
+ elif execution_device is not None:
+ devices = {name: param.device for name, param in module.named_parameters(recurse=False)}
+ try:
+ for name in devices:
+ set_module_tensor_to_device(module, name, execution_device)
+ yield
+ finally:
+ for name, device in devices.items():
+ set_module_tensor_to_device(module, name, device)
+
+ else:
+ yield
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/offload.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/offload.py
new file mode 100644
index 0000000000000000000000000000000000000000..da8cfaf3ebf7f2965f408e2b952103ac26868647
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/offload.py
@@ -0,0 +1,213 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import json
+import os
+from collections.abc import Mapping
+from typing import Optional, Union
+
+import numpy as np
+import torch
+from safetensors import safe_open
+
+
+def offload_weight(weight, weight_name, offload_folder, index=None):
+ dtype = None
+ # Check the string instead of the dtype to be compatible with versions of PyTorch that don't have bfloat16.
+ if str(weight.dtype) == "torch.bfloat16":
+ # Need to reinterpret the underlined data as int16 since NumPy does not handle bfloat16s.
+ weight = weight.view(torch.int16)
+ dtype = "bfloat16"
+ array = weight.cpu().numpy()
+ tensor_file = os.path.join(offload_folder, f"{weight_name}.dat")
+ if index is not None:
+ if dtype is None:
+ dtype = str(array.dtype)
+ index[weight_name] = {"dtype": dtype, "shape": list(array.shape)}
+ if array.ndim == 0:
+ array = array[None]
+ file_array = np.memmap(tensor_file, dtype=array.dtype, mode="w+", shape=array.shape)
+ file_array[:] = array[:]
+ file_array.flush()
+ return index
+
+
+def load_offloaded_weight(weight_file, weight_info):
+ shape = tuple(weight_info["shape"])
+ if shape == ():
+ # NumPy memory-mapped arrays can't have 0 dims so it was saved as 1d tensor
+ shape = (1,)
+
+ dtype = weight_info["dtype"]
+ if dtype == "bfloat16":
+ # NumPy does not support bfloat16 so this was saved as a int16
+ dtype = "int16"
+
+ weight = np.memmap(weight_file, dtype=dtype, shape=shape, mode="r")
+
+ if len(weight_info["shape"]) == 0:
+ weight = weight[0]
+ weight = torch.tensor(weight)
+ if weight_info["dtype"] == "bfloat16":
+ weight = weight.view(torch.bfloat16)
+
+ return weight
+
+
+def save_offload_index(index, offload_folder):
+ if index is None or len(index) == 0:
+ # Nothing to save
+ return
+
+ offload_index_file = os.path.join(offload_folder, "index.json")
+ if os.path.isfile(offload_index_file):
+ with open(offload_index_file, encoding="utf-8") as f:
+ current_index = json.load(f)
+ else:
+ current_index = {}
+ current_index.update(index)
+
+ with open(offload_index_file, "w", encoding="utf-8") as f:
+ json.dump(current_index, f, indent=2)
+
+
+def offload_state_dict(save_dir: Union[str, os.PathLike], state_dict: dict[str, torch.Tensor]):
+ """
+ Offload a state dict in a given folder.
+
+ Args:
+ save_dir (`str` or `os.PathLike`):
+ The directory in which to offload the state dict.
+ state_dict (`Dict[str, torch.Tensor]`):
+ The dictionary of tensors to offload.
+ """
+ os.makedirs(save_dir, exist_ok=True)
+ index = {}
+ for name, parameter in state_dict.items():
+ index = offload_weight(parameter, name, save_dir, index=index)
+
+ # Update index
+ save_offload_index(index, save_dir)
+
+
+class PrefixedDataset(Mapping):
+ """
+ Will access keys in a given dataset by adding a prefix.
+
+ Args:
+ dataset (`Mapping`): Any map with string keys.
+ prefix (`str`): A prefix to add when trying to access any element in the underlying dataset.
+ """
+
+ def __init__(self, dataset: Mapping, prefix: str):
+ self.dataset = dataset
+ self.prefix = prefix
+
+ def __getitem__(self, key):
+ return self.dataset[f"{self.prefix}{key}"]
+
+ def __iter__(self):
+ return iter([key for key in self.dataset if key.startswith(self.prefix)])
+
+ def __len__(self):
+ return len(self.dataset)
+
+
+class OffloadedWeightsLoader(Mapping):
+ """
+ A collection that loads weights stored in a given state dict or memory-mapped on disk.
+
+ Args:
+ state_dict (`Dict[str, torch.Tensor]`, *optional*):
+ A dictionary parameter name to tensor.
+ save_folder (`str` or `os.PathLike`, *optional*):
+ The directory in which the weights are stored (by `offload_state_dict` for instance).
+ index (`Dict`, *optional*):
+ A dictionary from weight name to their information (`dtype`/ `shape` or safetensors filename). Will default
+ to the index saved in `save_folder`.
+ """
+
+ def __init__(
+ self,
+ state_dict: Optional[dict[str, torch.Tensor]] = None,
+ save_folder: Optional[Union[str, os.PathLike]] = None,
+ index: Optional[Mapping] = None,
+ device=None,
+ ):
+ if state_dict is None and save_folder is None and index is None:
+ raise ValueError("Need either a `state_dict`, a `save_folder` or an `index` containing offloaded weights.")
+
+ self.state_dict = {} if state_dict is None else state_dict
+ self.save_folder = save_folder
+ if index is None and save_folder is not None:
+ with open(os.path.join(save_folder, "index.json")) as f:
+ index = json.load(f)
+ self.index = {} if index is None else index
+ self.all_keys = list(self.state_dict.keys())
+ self.all_keys.extend([key for key in self.index if key not in self.all_keys])
+ self.device = device
+
+ def __getitem__(self, key: str):
+ # State dict gets priority
+ if key in self.state_dict:
+ return self.state_dict[key]
+ weight_info = self.index[key]
+ if weight_info.get("safetensors_file") is not None:
+ device = "cpu" if self.device is None else self.device
+ tensor = None
+ try:
+ with safe_open(weight_info["safetensors_file"], framework="pt", device=device) as f:
+ tensor = f.get_tensor(weight_info.get("weight_name", key))
+ except TypeError:
+ # if failed to get_tensor on the device, such as bf16 on mps, try to load it on CPU first
+ with safe_open(weight_info["safetensors_file"], framework="pt", device="cpu") as f:
+ tensor = f.get_tensor(weight_info.get("weight_name", key))
+
+ if "dtype" in weight_info:
+ tensor = tensor.to(getattr(torch, weight_info["dtype"]))
+
+ if tensor.device != torch.device(device):
+ tensor = tensor.to(device)
+ return tensor
+
+ weight_file = os.path.join(self.save_folder, f"{key}.dat")
+ return load_offloaded_weight(weight_file, weight_info)
+
+ def __iter__(self):
+ return iter(self.all_keys)
+
+ def __len__(self):
+ return len(self.all_keys)
+
+
+def extract_submodules_state_dict(state_dict: dict[str, torch.Tensor], submodule_names: list[str]):
+ """
+ Extract the sub state-dict corresponding to a list of given submodules.
+
+ Args:
+ state_dict (`Dict[str, torch.Tensor]`): The state dict to extract from.
+ submodule_names (`List[str]`): The list of submodule names we want to extract.
+ """
+ result = {}
+ for module_name in submodule_names:
+ # We want to catch module_name parameter (module_name.xxx) or potentially module_name, but not any of the
+ # submodules that could being like module_name (transformers.h.1 and transformers.h.10 for instance)
+ result.update(
+ {
+ key: param
+ for key, param in state_dict.items()
+ if key == module_name or key.startswith(module_name + ".")
+ }
+ )
+ return result
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/operations.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/operations.py
new file mode 100644
index 0000000000000000000000000000000000000000..2357fdf03ba533714bf517e67269b3be36a78e39
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/operations.py
@@ -0,0 +1,867 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+A set of basic tensor ops compatible with tpu, gpu, and multigpu
+"""
+
+import pickle
+import warnings
+from collections.abc import Mapping
+from contextlib import contextmanager, nullcontext
+from functools import update_wrapper, wraps
+from typing import Any
+
+import torch
+
+from ..state import AcceleratorState, PartialState
+from .constants import TORCH_DISTRIBUTED_OPERATION_TYPES
+from .dataclasses import DistributedType, TensorInformation
+from .imports import (
+ is_npu_available,
+ is_torch_distributed_available,
+ is_torch_xla_available,
+)
+from .versions import is_torch_version
+
+
+if is_torch_xla_available():
+ import torch_xla.core.xla_model as xm
+
+if is_torch_distributed_available():
+ from torch.distributed import ReduceOp
+
+
+def is_torch_tensor(tensor):
+ return isinstance(tensor, torch.Tensor)
+
+
+def is_torch_xpu_tensor(tensor):
+ return isinstance(
+ tensor,
+ torch.xpu.FloatTensor,
+ torch.xpu.ByteTensor,
+ torch.xpu.IntTensor,
+ torch.xpu.LongTensor,
+ torch.xpu.HalfTensor,
+ torch.xpu.DoubleTensor,
+ torch.xpu.BFloat16Tensor,
+ )
+
+
+def is_tensor_information(tensor_info):
+ return isinstance(tensor_info, TensorInformation)
+
+
+def is_namedtuple(data):
+ """
+ Checks if `data` is a `namedtuple` or not. Can have false positives, but only if a user is trying to mimic a
+ `namedtuple` perfectly.
+ """
+ return isinstance(data, tuple) and hasattr(data, "_asdict") and hasattr(data, "_fields")
+
+
+def honor_type(obj, generator):
+ """
+ Cast a generator to the same type as obj (list, tuple, or namedtuple)
+ """
+ # Some objects may not be able to instantiate from a generator directly
+ if is_namedtuple(obj):
+ return type(obj)(*list(generator))
+ else:
+ return type(obj)(generator)
+
+
+def recursively_apply(func, data, *args, test_type=is_torch_tensor, error_on_other_type=False, **kwargs):
+ """
+ Recursively apply a function on a data structure that is a nested list/tuple/dictionary of a given base type.
+
+ Args:
+ func (`callable`):
+ The function to recursively apply.
+ data (nested list/tuple/dictionary of `main_type`):
+ The data on which to apply `func`
+ *args:
+ Positional arguments that will be passed to `func` when applied on the unpacked data.
+ main_type (`type`, *optional*, defaults to `torch.Tensor`):
+ The base type of the objects to which apply `func`.
+ error_on_other_type (`bool`, *optional*, defaults to `False`):
+ Whether to return an error or not if after unpacking `data`, we get on an object that is not of type
+ `main_type`. If `False`, the function will leave objects of types different than `main_type` unchanged.
+ **kwargs (additional keyword arguments, *optional*):
+ Keyword arguments that will be passed to `func` when applied on the unpacked data.
+
+ Returns:
+ The same data structure as `data` with `func` applied to every object of type `main_type`.
+ """
+ if isinstance(data, (tuple, list)):
+ return honor_type(
+ data,
+ (
+ recursively_apply(
+ func, o, *args, test_type=test_type, error_on_other_type=error_on_other_type, **kwargs
+ )
+ for o in data
+ ),
+ )
+ elif isinstance(data, Mapping):
+ return type(data)(
+ {
+ k: recursively_apply(
+ func, v, *args, test_type=test_type, error_on_other_type=error_on_other_type, **kwargs
+ )
+ for k, v in data.items()
+ }
+ )
+ elif test_type(data):
+ return func(data, *args, **kwargs)
+ elif error_on_other_type:
+ raise TypeError(
+ f"Unsupported types ({type(data)}) passed to `{func.__name__}`. Only nested list/tuple/dicts of "
+ f"objects that are valid for `{test_type.__name__}` should be passed."
+ )
+ return data
+
+
+def send_to_device(tensor, device, non_blocking=False, skip_keys=None):
+ """
+ Recursively sends the elements in a nested list/tuple/dictionary of tensors to a given device.
+
+ Args:
+ tensor (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to send to a given device.
+ device (`torch.device`):
+ The device to send the data to.
+
+ Returns:
+ The same data structure as `tensor` with all tensors sent to the proper device.
+ """
+ if is_torch_tensor(tensor) or hasattr(tensor, "to"):
+ # `torch.Tensor.to("npu")` could not find context when called for the first time (see this [issue](https://gitee.com/ascend/pytorch/issues/I8KECW?from=project-issue)).
+ if device == "npu":
+ device = "npu:0"
+ try:
+ return tensor.to(device, non_blocking=non_blocking)
+ except TypeError: # .to() doesn't accept non_blocking as kwarg
+ return tensor.to(device)
+ except AssertionError as error:
+ # `torch.Tensor.to()` is not supported by `torch_npu` (see this [issue](https://github.com/Ascend/pytorch/issues/16)).
+ # This call is inside the try-block since is_npu_available is not supported by torch.compile.
+ if is_npu_available():
+ if isinstance(device, int):
+ device = f"npu:{device}"
+ else:
+ raise error
+ try:
+ return tensor.to(device, non_blocking=non_blocking)
+ except TypeError: # .to() doesn't accept non_blocking as kwarg
+ return tensor.to(device)
+ elif isinstance(tensor, (tuple, list)):
+ return honor_type(
+ tensor, (send_to_device(t, device, non_blocking=non_blocking, skip_keys=skip_keys) for t in tensor)
+ )
+ elif isinstance(tensor, Mapping):
+ if isinstance(skip_keys, str):
+ skip_keys = [skip_keys]
+ elif skip_keys is None:
+ skip_keys = []
+ return type(tensor)(
+ {
+ k: t if k in skip_keys else send_to_device(t, device, non_blocking=non_blocking, skip_keys=skip_keys)
+ for k, t in tensor.items()
+ }
+ )
+ else:
+ return tensor
+
+
+def get_data_structure(data):
+ """
+ Recursively gathers the information needed to rebuild a nested list/tuple/dictionary of tensors.
+
+ Args:
+ data (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to send to analyze.
+
+ Returns:
+ The same data structure as `data` with [`~utils.TensorInformation`] instead of tensors.
+ """
+
+ def _get_data_structure(tensor):
+ return TensorInformation(shape=tensor.shape, dtype=tensor.dtype)
+
+ return recursively_apply(_get_data_structure, data)
+
+
+def get_shape(data):
+ """
+ Recursively gathers the shape of a nested list/tuple/dictionary of tensors as a list.
+
+ Args:
+ data (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to send to analyze.
+
+ Returns:
+ The same data structure as `data` with lists of tensor shapes instead of tensors.
+ """
+
+ def _get_shape(tensor):
+ return list(tensor.shape)
+
+ return recursively_apply(_get_shape, data)
+
+
+def initialize_tensors(data_structure):
+ """
+ Recursively initializes tensors from a nested list/tuple/dictionary of [`~utils.TensorInformation`].
+
+ Returns:
+ The same data structure as `data` with tensors instead of [`~utils.TensorInformation`].
+ """
+
+ def _initialize_tensor(tensor_info):
+ return torch.empty(*tensor_info.shape, dtype=tensor_info.dtype)
+
+ return recursively_apply(_initialize_tensor, data_structure, test_type=is_tensor_information)
+
+
+def find_batch_size(data):
+ """
+ Recursively finds the batch size in a nested list/tuple/dictionary of lists of tensors.
+
+ Args:
+ data (nested list/tuple/dictionary of `torch.Tensor`): The data from which to find the batch size.
+
+ Returns:
+ `int`: The batch size.
+ """
+ if isinstance(data, (tuple, list, Mapping)) and (len(data) == 0):
+ raise ValueError(f"Cannot find the batch size from empty {type(data)}.")
+
+ if isinstance(data, (tuple, list)):
+ return find_batch_size(data[0])
+ elif isinstance(data, Mapping):
+ for k in data.keys():
+ return find_batch_size(data[k])
+ elif not isinstance(data, torch.Tensor):
+ raise TypeError(f"Can only find the batch size of tensors but got {type(data)}.")
+ return data.shape[0]
+
+
+def ignorant_find_batch_size(data):
+ """
+ Same as [`utils.operations.find_batch_size`] except will ignore if `ValueError` and `TypeErrors` are raised
+
+ Args:
+ data (nested list/tuple/dictionary of `torch.Tensor`): The data from which to find the batch size.
+
+ Returns:
+ `int`: The batch size.
+ """
+ try:
+ return find_batch_size(data)
+ except (ValueError, TypeError):
+ pass
+ return None
+
+
+def listify(data):
+ """
+ Recursively finds tensors in a nested list/tuple/dictionary and converts them to a list of numbers.
+
+ Args:
+ data (nested list/tuple/dictionary of `torch.Tensor`): The data from which to convert to regular numbers.
+
+ Returns:
+ The same data structure as `data` with lists of numbers instead of `torch.Tensor`.
+ """
+
+ def _convert_to_list(tensor):
+ tensor = tensor.detach().cpu()
+ if tensor.dtype == torch.bfloat16:
+ # As of Numpy 1.21.4, NumPy does not support bfloat16 (see
+ # https://github.com/numpy/numpy/blob/a47ecdea856986cd60eabbd53265c2ca5916ad5d/doc/source/user/basics.types.rst ).
+ # Until Numpy adds bfloat16, we must convert float32.
+ tensor = tensor.to(torch.float32)
+ return tensor.tolist()
+
+ return recursively_apply(_convert_to_list, data)
+
+
+def _tpu_gather(tensor):
+ def _tpu_gather_one(tensor):
+ if tensor.ndim == 0:
+ tensor = tensor.clone()[None]
+
+ # Can only gather contiguous tensors
+ if not tensor.is_contiguous():
+ tensor = tensor.contiguous()
+ return xm.all_gather(tensor)
+
+ res = recursively_apply(_tpu_gather_one, tensor, error_on_other_type=True)
+ xm.mark_step()
+ return res
+
+
+def _gpu_gather(tensor):
+ state = PartialState()
+ gather_op = torch.distributed.all_gather_into_tensor
+
+ # NOTE: need manually synchronize to workaourd a INT64 collectives bug in oneCCL before torch 2.9.0
+ if state.device.type == "xpu" and is_torch_version("<=", "2.8"):
+ torch.xpu.synchronize()
+
+ def _gpu_gather_one(tensor):
+ if tensor.ndim == 0:
+ tensor = tensor.clone()[None]
+
+ # Can only gather contiguous tensors
+ if not tensor.is_contiguous():
+ tensor = tensor.contiguous()
+
+ if state.backend is not None and state.backend != "gloo":
+ # We use `empty` as `all_gather_into_tensor` slightly
+ # differs from `all_gather` for better efficiency,
+ # and we rely on the number of items in the tensor
+ # rather than its direct shape
+ output_tensors = torch.empty(
+ state.num_processes * tensor.numel(),
+ dtype=tensor.dtype,
+ device=state.device,
+ )
+ gather_op(output_tensors, tensor)
+ return output_tensors.view(-1, *tensor.size()[1:])
+ else:
+ # a backend of `None` is always CPU
+ # also gloo does not support `all_gather_into_tensor`,
+ # which will result in a larger memory overhead for the op
+ output_tensors = [torch.empty_like(tensor) for _ in range(state.num_processes)]
+ torch.distributed.all_gather(output_tensors, tensor)
+ return torch.cat(output_tensors, dim=0)
+
+ return recursively_apply(_gpu_gather_one, tensor, error_on_other_type=True)
+
+
+class DistributedOperationException(Exception):
+ """
+ An exception class for distributed operations. Raised if the operation cannot be performed due to the shape of the
+ tensors.
+ """
+
+ pass
+
+
+def verify_operation(function):
+ """
+ Verifies that `tensor` is the same shape across all processes. Only ran if `PartialState().debug` is `True`.
+ """
+
+ @wraps(function)
+ def wrapper(*args, **kwargs):
+ if PartialState().distributed_type == DistributedType.NO or not PartialState().debug:
+ return function(*args, **kwargs)
+ operation = f"{function.__module__}.{function.__name__}"
+ if "tensor" in kwargs:
+ tensor = kwargs["tensor"]
+ else:
+ tensor = args[0]
+ if PartialState().device.type != find_device(tensor).type:
+ raise DistributedOperationException(
+ f"One or more of the tensors passed to {operation} were not on the {tensor.device.type} while the `Accelerator` is configured for {PartialState().device.type}. "
+ f"Please move it to the {PartialState().device.type} before calling {operation}."
+ )
+ shapes = get_shape(tensor)
+ output = gather_object([shapes])
+ if output[0] is not None:
+ are_same = output.count(output[0]) == len(output)
+ if not are_same:
+ process_shape_str = "\n - ".join([f"Process {i}: {shape}" for i, shape in enumerate(output)])
+ raise DistributedOperationException(
+ f"Cannot apply desired operation due to shape mismatches. "
+ "All shapes across devices must be valid."
+ f"\n\nOperation: `{operation}`\nInput shapes:\n - {process_shape_str}"
+ )
+ return function(*args, **kwargs)
+
+ return wrapper
+
+
+def chained_operation(function):
+ """
+ Checks that `verify_operation` failed and if so reports a more helpful error chaining the existing
+ `DistributedOperationException`.
+ """
+
+ @wraps(function)
+ def wrapper(*args, **kwargs):
+ try:
+ return function(*args, **kwargs)
+ except DistributedOperationException as e:
+ operation = f"{function.__module__}.{function.__name__}"
+ raise DistributedOperationException(
+ f"Error found while calling `{operation}`. Please see the earlier error for more details."
+ ) from e
+
+ return wrapper
+
+
+@verify_operation
+def gather(tensor):
+ """
+ Recursively gather tensor in a nested list/tuple/dictionary of tensors from all devices.
+
+ Args:
+ tensor (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to gather.
+
+ Returns:
+ The same data structure as `tensor` with all tensors sent to the proper device.
+ """
+ if PartialState().distributed_type == DistributedType.XLA:
+ return _tpu_gather(tensor)
+ elif PartialState().distributed_type in TORCH_DISTRIBUTED_OPERATION_TYPES:
+ return _gpu_gather(tensor)
+ else:
+ return tensor
+
+
+def _gpu_gather_object(object: Any):
+ output_objects = [None for _ in range(PartialState().num_processes)]
+ torch.distributed.all_gather_object(output_objects, object)
+ # all_gather_object returns a list of lists, so we need to flatten it
+ return [x for y in output_objects for x in y]
+
+
+def gather_object(object: Any):
+ """
+ Recursively gather object in a nested list/tuple/dictionary of objects from all devices.
+
+ Args:
+ object (nested list/tuple/dictionary of picklable object):
+ The data to gather.
+
+ Returns:
+ The same data structure as `object` with all the objects sent to every device.
+ """
+ if PartialState().distributed_type == DistributedType.XLA:
+ raise NotImplementedError("gather objects in TPU is not supported")
+ elif PartialState().distributed_type in TORCH_DISTRIBUTED_OPERATION_TYPES:
+ return _gpu_gather_object(object)
+ else:
+ return object
+
+
+def _gpu_broadcast(data, src=0):
+ def _gpu_broadcast_one(tensor, src=0):
+ torch.distributed.broadcast(tensor, src=src)
+ return tensor
+
+ return recursively_apply(_gpu_broadcast_one, data, error_on_other_type=True, src=src)
+
+
+def _tpu_broadcast(tensor, src=0, name="broadcast tensor"):
+ if isinstance(tensor, (list, tuple)):
+ return honor_type(tensor, (_tpu_broadcast(t, name=f"{name}_{i}") for i, t in enumerate(tensor)))
+ elif isinstance(tensor, Mapping):
+ return type(tensor)({k: _tpu_broadcast(v, name=f"{name}_{k}") for k, v in tensor.items()})
+ return xm.mesh_reduce(name, tensor, lambda x: x[src])
+
+
+TENSOR_TYPE_TO_INT = {
+ torch.float: 1,
+ torch.double: 2,
+ torch.half: 3,
+ torch.bfloat16: 4,
+ torch.uint8: 5,
+ torch.int8: 6,
+ torch.int16: 7,
+ torch.int32: 8,
+ torch.int64: 9,
+ torch.bool: 10,
+}
+
+TENSOR_INT_TO_DTYPE = {v: k for k, v in TENSOR_TYPE_TO_INT.items()}
+
+
+def gather_tensor_shape(tensor):
+ """
+ Grabs the shape of `tensor` only available on one process and returns a tensor of its shape
+ """
+ # Allocate 80 bytes to store the shape
+ max_tensor_dimension = 2**20
+ state = PartialState()
+ base_tensor = torch.empty(max_tensor_dimension, dtype=torch.int, device=state.device)
+
+ # Since PyTorch can't just send a tensor to another GPU without
+ # knowing its size, we store the size of the tensor with data
+ # in an allocation
+ if tensor is not None:
+ shape = tensor.shape
+ tensor_dtype = TENSOR_TYPE_TO_INT[tensor.dtype]
+ base_tensor[: len(shape) + 1] = torch.tensor(list(shape) + [tensor_dtype], dtype=int)
+ # Perform a reduction to copy the size data onto all GPUs
+ base_tensor = reduce(base_tensor, reduction="sum")
+ base_tensor = base_tensor[base_tensor.nonzero()]
+ # The last non-zero data contains the coded dtype the source tensor is
+ dtype = int(base_tensor[-1:][0])
+ base_tensor = base_tensor[:-1]
+ return base_tensor, dtype
+
+
+def copy_tensor_to_devices(tensor=None) -> torch.Tensor:
+ """
+ Copies a tensor that only exists on a single device and broadcasts it to other devices. Differs from `broadcast` as
+ each worker doesn't need to know its shape when used (and tensor can be `None`)
+
+ Args:
+ tensor (`torch.tensor`):
+ The tensor that should be sent to all devices. Must only have it be defined on a single device, the rest
+ should be `None`.
+ """
+ state = PartialState()
+ shape, dtype = gather_tensor_shape(tensor)
+ if tensor is None:
+ tensor = torch.zeros(shape, dtype=TENSOR_INT_TO_DTYPE[dtype]).to(state.device)
+ return reduce(tensor, reduction="sum")
+
+
+@verify_operation
+def broadcast(tensor, from_process: int = 0):
+ """
+ Recursively broadcast tensor in a nested list/tuple/dictionary of tensors to all devices.
+
+ Args:
+ tensor (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to gather.
+ from_process (`int`, *optional*, defaults to 0):
+ The process from which to send the data
+
+ Returns:
+ The same data structure as `tensor` with all tensors broadcasted to the proper device.
+ """
+ if PartialState().distributed_type == DistributedType.XLA:
+ return _tpu_broadcast(tensor, src=from_process, name="accelerate.utils.broadcast")
+ elif PartialState().distributed_type in TORCH_DISTRIBUTED_OPERATION_TYPES:
+ return _gpu_broadcast(tensor, src=from_process)
+ else:
+ return tensor
+
+
+def broadcast_object_list(object_list, from_process: int = 0):
+ """
+ Broadcast a list of picklable objects from one process to the others.
+
+ Args:
+ object_list (list of picklable objects):
+ The list of objects to broadcast. This list will be modified inplace.
+ from_process (`int`, *optional*, defaults to 0):
+ The process from which to send the data.
+
+ Returns:
+ The same list containing the objects from process 0.
+ """
+ if PartialState().distributed_type == DistributedType.XLA:
+ for i, obj in enumerate(object_list):
+ object_list[i] = xm.mesh_reduce("accelerate.utils.broadcast_object_list", obj, lambda x: x[from_process])
+ elif PartialState().distributed_type in TORCH_DISTRIBUTED_OPERATION_TYPES:
+ torch.distributed.broadcast_object_list(object_list, src=from_process)
+ return object_list
+
+
+def slice_tensors(data, tensor_slice, process_index=None, num_processes=None):
+ """
+ Recursively takes a slice in a nested list/tuple/dictionary of tensors.
+
+ Args:
+ data (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to slice.
+ tensor_slice (`slice`):
+ The slice to take.
+
+ Returns:
+ The same data structure as `data` with all the tensors slices.
+ """
+
+ def _slice_tensor(tensor, tensor_slice):
+ return tensor[tensor_slice]
+
+ return recursively_apply(_slice_tensor, data, tensor_slice)
+
+
+def concatenate(data, dim=0):
+ """
+ Recursively concatenate the tensors in a nested list/tuple/dictionary of lists of tensors with the same shape.
+
+ Args:
+ data (nested list/tuple/dictionary of lists of tensors `torch.Tensor`):
+ The data to concatenate.
+ dim (`int`, *optional*, defaults to 0):
+ The dimension on which to concatenate.
+
+ Returns:
+ The same data structure as `data` with all the tensors concatenated.
+ """
+ if isinstance(data[0], (tuple, list)):
+ return honor_type(data[0], (concatenate([d[i] for d in data], dim=dim) for i in range(len(data[0]))))
+ elif isinstance(data[0], Mapping):
+ return type(data[0])({k: concatenate([d[k] for d in data], dim=dim) for k in data[0].keys()})
+ elif not isinstance(data[0], torch.Tensor):
+ raise TypeError(f"Can only concatenate tensors but got {type(data[0])}")
+ return torch.cat(data, dim=dim)
+
+
+class CannotPadNestedTensorWarning(UserWarning):
+ pass
+
+
+@chained_operation
+def pad_across_processes(tensor, dim=0, pad_index=0, pad_first=False):
+ """
+ Recursively pad the tensors in a nested list/tuple/dictionary of tensors from all devices to the same size so they
+ can safely be gathered.
+
+ Args:
+ tensor (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to gather.
+ dim (`int`, *optional*, defaults to 0):
+ The dimension on which to pad.
+ pad_index (`int`, *optional*, defaults to 0):
+ The value with which to pad.
+ pad_first (`bool`, *optional*, defaults to `False`):
+ Whether to pad at the beginning or the end.
+ """
+
+ def _pad_across_processes(tensor, dim=0, pad_index=0, pad_first=False):
+ if getattr(tensor, "is_nested", False):
+ warnings.warn(
+ "Cannot pad nested tensors without more information. Leaving unprocessed.",
+ CannotPadNestedTensorWarning,
+ )
+ return tensor
+ if dim >= len(tensor.shape) or dim < -len(tensor.shape):
+ return tensor
+ # Convert negative dimensions to non-negative
+ if dim < 0:
+ dim += len(tensor.shape)
+
+ # Gather all sizes
+ size = torch.tensor(tensor.shape, device=tensor.device)[None]
+ sizes = gather(size).cpu()
+ # Then pad to the maximum size
+ max_size = max(s[dim] for s in sizes)
+ if max_size == tensor.shape[dim]:
+ return tensor
+
+ old_size = tensor.shape
+ new_size = list(old_size)
+ new_size[dim] = max_size
+ new_tensor = tensor.new_zeros(tuple(new_size)) + pad_index
+ if pad_first:
+ indices = tuple(
+ slice(max_size - old_size[dim], max_size) if i == dim else slice(None) for i in range(len(new_size))
+ )
+ else:
+ indices = tuple(slice(0, old_size[dim]) if i == dim else slice(None) for i in range(len(new_size)))
+ new_tensor[indices] = tensor
+ return new_tensor
+
+ return recursively_apply(
+ _pad_across_processes, tensor, error_on_other_type=True, dim=dim, pad_index=pad_index, pad_first=pad_first
+ )
+
+
+def pad_input_tensors(tensor, batch_size, num_processes, dim=0):
+ """
+ Takes a `tensor` of arbitrary size and pads it so that it can work given `num_processes` needed dimensions.
+
+ New tensors are just the last input repeated.
+
+ E.g.:
+ Tensor: ([3,4,4]) Num processes: 4 Expected result shape: ([4,4,4])
+
+ """
+
+ def _pad_input_tensors(tensor, batch_size, num_processes, dim=0):
+ remainder = batch_size // num_processes
+ last_inputs = batch_size - (remainder * num_processes)
+ if batch_size // num_processes == 0:
+ to_pad = num_processes - batch_size
+ else:
+ to_pad = num_processes - (batch_size // num_processes)
+ # In the rare case that `to_pad` is negative,
+ # we need to pad the last inputs - the found `to_pad`
+ if last_inputs > to_pad & to_pad < 1:
+ to_pad = last_inputs - to_pad
+ old_size = tensor.shape
+ new_size = list(old_size)
+ new_size[0] = batch_size + to_pad
+ new_tensor = tensor.new_zeros(tuple(new_size))
+ indices = tuple(slice(0, old_size[dim]) if i == dim else slice(None) for i in range(len(new_size)))
+ new_tensor[indices] = tensor
+ return new_tensor
+
+ return recursively_apply(
+ _pad_input_tensors,
+ tensor,
+ error_on_other_type=True,
+ batch_size=batch_size,
+ num_processes=num_processes,
+ dim=dim,
+ )
+
+
+@verify_operation
+def reduce(tensor, reduction="mean", scale=1.0):
+ """
+ Recursively reduce the tensors in a nested list/tuple/dictionary of lists of tensors across all processes by the
+ mean of a given operation.
+
+ Args:
+ tensor (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to reduce.
+ reduction (`str`, *optional*, defaults to `"mean"`):
+ A reduction method. Can be of "mean", "sum", or "none"
+ scale (`float`, *optional*):
+ A default scaling value to be applied after the reduce, only valid on XLA.
+
+ Returns:
+ The same data structure as `data` with all the tensors reduced.
+ """
+
+ def _reduce_across_processes(tensor, reduction="mean", scale=1.0):
+ state = PartialState()
+ cloned_tensor = tensor.clone()
+ if state.distributed_type == DistributedType.NO:
+ return cloned_tensor
+ if state.distributed_type == DistributedType.XLA:
+ # Some processes may have different HLO graphs than other
+ # processes, for example in the breakpoint API
+ # accelerator.set_trigger(). Use mark_step to make HLOs
+ # the same on all processes.
+ xm.mark_step()
+ xm.all_reduce(xm.REDUCE_SUM, [cloned_tensor], scale)
+ xm.mark_step()
+ elif state.distributed_type.value in TORCH_DISTRIBUTED_OPERATION_TYPES:
+ torch.distributed.all_reduce(cloned_tensor, ReduceOp.SUM)
+ if reduction == "mean":
+ cloned_tensor /= state.num_processes
+ return cloned_tensor
+
+ return recursively_apply(
+ _reduce_across_processes, tensor, error_on_other_type=True, reduction=reduction, scale=scale
+ )
+
+
+def convert_to_fp32(tensor):
+ """
+ Recursively converts the elements nested list/tuple/dictionary of tensors in FP16/BF16 precision to FP32.
+
+ Args:
+ tensor (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to convert from FP16/BF16 to FP32.
+
+ Returns:
+ The same data structure as `tensor` with all tensors that were in FP16/BF16 precision converted to FP32.
+ """
+
+ def _convert_to_fp32(tensor):
+ return tensor.float()
+
+ def _is_fp16_bf16_tensor(tensor):
+ return (is_torch_tensor(tensor) or hasattr(tensor, "dtype")) and tensor.dtype in (
+ torch.float16,
+ torch.bfloat16,
+ )
+
+ return recursively_apply(_convert_to_fp32, tensor, test_type=_is_fp16_bf16_tensor)
+
+
+class ConvertOutputsToFp32:
+ """
+ Decorator to apply to a function outputting tensors (like a model forward pass) that ensures the outputs in FP16
+ precision will be convert back to FP32.
+
+ Args:
+ model_forward (`Callable`):
+ The function which outputs we want to treat.
+
+ Returns:
+ The same function as `model_forward` but with converted outputs.
+ """
+
+ def __init__(self, model_forward):
+ self.model_forward = model_forward
+ update_wrapper(self, model_forward)
+
+ def __call__(self, *args, **kwargs):
+ return convert_to_fp32(self.model_forward(*args, **kwargs))
+
+ def __getstate__(self):
+ raise pickle.PicklingError(
+ "Cannot pickle a prepared model with automatic mixed precision, please unwrap the model with `Accelerator.unwrap_model(model)` before pickling it."
+ )
+
+
+def convert_outputs_to_fp32(model_forward):
+ model_forward = ConvertOutputsToFp32(model_forward)
+
+ def forward(*args, **kwargs):
+ return model_forward(*args, **kwargs)
+
+ # To act like a decorator so that it can be popped when doing `extract_model_from_parallel`
+ forward.__wrapped__ = model_forward
+
+ return forward
+
+
+def find_device(data):
+ """
+ Finds the device on which a nested dict/list/tuple of tensors lies (assuming they are all on the same device).
+
+ Args:
+ (nested list/tuple/dictionary of `torch.Tensor`): The data we want to know the device of.
+ """
+ if isinstance(data, Mapping):
+ for obj in data.values():
+ device = find_device(obj)
+ if device is not None:
+ return device
+ elif isinstance(data, (tuple, list)):
+ for obj in data:
+ device = find_device(obj)
+ if device is not None:
+ return device
+ elif isinstance(data, torch.Tensor):
+ return data.device
+
+
+@contextmanager
+def GatheredParameters(params, modifier_rank=None, fwd_module=None, enabled=True):
+ """
+ Wrapper around `deepspeed.runtime.zero.GatheredParameters`, but if Zero-3 is not enabled, will be a no-op context
+ manager.
+ """
+ # We need to use the `AcceleratorState` here since it has access to the deepspeed plugin
+ if AcceleratorState().distributed_type != DistributedType.DEEPSPEED or (
+ AcceleratorState().deepspeed_plugin is not None
+ and not AcceleratorState().deepspeed_plugin.is_zero3_init_enabled()
+ ):
+ gather_param_context = nullcontext()
+ else:
+ import deepspeed
+
+ gather_param_context = deepspeed.zero.GatheredParameters(
+ params, modifier_rank=modifier_rank, fwd_module=fwd_module, enabled=enabled
+ )
+ with gather_param_context:
+ yield
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/other.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/other.py
new file mode 100644
index 0000000000000000000000000000000000000000..69bed25cb66b31e32cbc984e8779af875b0cfde1
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/other.py
@@ -0,0 +1,561 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import collections
+import platform
+import re
+import socket
+from codecs import encode
+from collections import OrderedDict
+from functools import partial, reduce
+from types import MethodType
+from typing import Optional
+
+import numpy as np
+import torch
+from packaging.version import Version
+from safetensors.torch import save_file as safe_save_file
+
+from ..commands.config.default import write_basic_config # noqa: F401
+from ..logging import get_logger
+from ..state import PartialState
+from .constants import FSDP_PYTORCH_VERSION
+from .dataclasses import DistributedType
+from .imports import (
+ is_deepspeed_available,
+ is_numpy_available,
+ is_torch_distributed_available,
+ is_torch_xla_available,
+ is_weights_only_available,
+)
+from .modeling import id_tensor_storage
+from .transformer_engine import convert_model
+from .versions import is_torch_version
+
+
+logger = get_logger(__name__)
+
+
+if is_torch_xla_available():
+ import torch_xla.core.xla_model as xm
+
+
+def is_compiled_module(module: torch.nn.Module) -> bool:
+ """
+ Check whether the module was compiled with torch.compile()
+ """
+ if not hasattr(torch, "_dynamo"):
+ return False
+
+ return isinstance(module, torch._dynamo.eval_frame.OptimizedModule)
+
+
+def has_compiled_regions(module: torch.nn.Module) -> bool:
+ """
+ Check whether the module has submodules that were compiled with `torch.compile()`.
+ """
+ if not hasattr(torch, "_dynamo"):
+ return False
+
+ if module._modules:
+ for submodule in module.modules():
+ if isinstance(submodule, torch._dynamo.eval_frame.OptimizedModule):
+ return True
+
+ return False
+
+
+def is_repeated_blocks(module: torch.nn.Module) -> bool:
+ """
+ Check whether the module is a repeated block, i.e. `torch.nn.ModuleList` with all children of the same class. This
+ is useful to determine whether we should apply regional compilation to the module.
+ """
+
+ return isinstance(module, torch.nn.ModuleList) and all(isinstance(m, module[0].__class__) for m in module)
+
+
+def has_repeated_blocks(module: torch.nn.Module) -> bool:
+ """
+ Check whether the module has repeated blocks, i.e. `torch.nn.ModuleList` with all children of the same class, at
+ any level of the module hierarchy. This is useful to determine whether we should apply regional compilation to the
+ module.
+ """
+ if module._modules:
+ for submodule in module.modules():
+ if is_repeated_blocks(submodule):
+ return True
+
+ return False
+
+
+def compile_regions(module: torch.nn.Module, **compile_kwargs) -> torch.nn.Module:
+ """
+ Performs regional compilation where we target repeated blocks of the same class and compile them sequentially to
+ hit the compiler's cache. For example, in `GPT2LMHeadModel`, the repeated block/class is `GPT2Block`, and can be
+ accessed as `model.transformer.h[0]`. The rest of the model (e.g. model.lm_head) is compiled separately.
+
+ This allows us to speed up the compilation overhead / cold start of models like LLMs and Transformers in general.
+ See https://pytorch.org/tutorials/recipes/regional_compilation.html for more details.
+
+ Args:
+ module (`torch.nn.Module`):
+ The model to compile.
+ **compile_kwargs:
+ Additional keyword arguments to pass to `torch.compile()`.
+
+ Returns:
+ `torch.nn.Module`: A new instance of the model with some compiled regions.
+
+ Example:
+ ```python
+ >>> from accelerate.utils import compile_regions
+ >>> from transformers import AutoModelForCausalLM
+
+ >>> model = AutoModelForCausalLM.from_pretrained("gpt2")
+ >>> compiled_model = compile_regions(model, mode="reduce-overhead")
+ >>> compiled_model.transformer.h[0]
+ OptimizedModule(
+ (_orig_mod): GPT2Block(
+ (ln_1): LayerNorm((768,), eps=1e-05, elementwise_affine=True)
+ (attn): GPT2Attention(
+ (c_attn): Conv1D(nf=2304, nx=768)
+ (c_proj): Conv1D(nf=768, nx=768)
+ (attn_dropout): Dropout(p=0.1, inplace=False)
+ (resid_dropout): Dropout(p=0.1, inplace=False)
+ )
+ (ln_2): LayerNorm((768,), eps=1e-05, elementwise_affine=True)
+ (mlp): GPT2MLP(
+ (c_fc): Conv1D(nf=3072, nx=768)
+ (c_proj): Conv1D(nf=768, nx=3072)
+ (act): NewGELUActivation()
+ (dropout): Dropout(p=0.1, inplace=False)
+ )
+ )
+ )
+ ```
+ """
+
+ def _compile_regions(module: torch.nn.Module, **compile_kwargs) -> torch.nn.Module:
+ if is_repeated_blocks(module):
+ new_module = torch.nn.ModuleList()
+ for submodule in module:
+ new_module.append(torch.compile(submodule, **compile_kwargs))
+ elif has_repeated_blocks(module):
+ new_module = module.__class__.__new__(module.__class__)
+ new_module.__dict__.update(module.__dict__)
+ new_module._modules = {}
+ for name, submodule in module.named_children():
+ new_module.add_module(name, _compile_regions(submodule, **compile_kwargs))
+ else:
+ new_module = torch.compile(module, **compile_kwargs)
+
+ return new_module
+
+ new_module = _compile_regions(module, **compile_kwargs)
+
+ if "_orig_mod" not in new_module.__dict__:
+ # Keeps a reference to the original module to decompile/unwrap it later
+ new_module.__dict__["_orig_mod"] = module
+
+ return new_module
+
+
+def compile_regions_deepspeed(module: torch.nn.Module, **compile_kwargs):
+ """
+ Performs regional compilation the same way as `compile_regions`, but specifically for `DeepSpeedEngine.module`.
+ Since the model is wrapped in a `DeepSpeedEngine` and has many added hooks, offloaded parameters, etc that
+ `torch.compile(...)` interferes with, version of trgional compilation uses the inplace `module.compile()` method
+ instead.
+
+ Args:
+ module (`torch.nn.Module`):
+ The model to compile.
+ **compile_kwargs:
+ Additional keyword arguments to pass to `module.compile()`.
+ """
+
+ if is_repeated_blocks(module):
+ for submodule in module:
+ submodule.compile(**compile_kwargs)
+ elif has_repeated_blocks(module):
+ for child in module.children():
+ compile_regions_deepspeed(child, **compile_kwargs)
+ else: # leaf node
+ module.compile(**compile_kwargs)
+
+
+def model_has_dtensor(model: torch.nn.Module) -> bool:
+ """
+ Check if the model has DTensor parameters.
+
+ Args:
+ model (`torch.nn.Module`):
+ The model to check.
+
+ Returns:
+ `bool`: Whether the model has DTensor parameters.
+ """
+ if is_torch_version(">=", "2.5.0"):
+ from torch.distributed.tensor import DTensor
+ else:
+ # from torch 2.0.0 (oldest supported accelerate torch version), DTensor is in torch.distributed._tensor
+ from torch.distributed._tensor import DTensor
+
+ return any(isinstance(p, DTensor) for p in model.parameters())
+
+
+def extract_model_from_parallel(
+ model, keep_fp32_wrapper: bool = True, keep_torch_compile: bool = True, recursive: bool = False
+):
+ """
+ Extract a model from its distributed containers.
+
+ Args:
+ model (`torch.nn.Module`):
+ The model to extract.
+ keep_fp32_wrapper (`bool`, *optional*):
+ Whether to remove mixed precision hooks from the model.
+ keep_torch_compile (`bool`, *optional*):
+ Whether to unwrap compiled model.
+ recursive (`bool`, *optional*, defaults to `False`):
+ Whether to recursively extract all cases of `module.module` from `model` as well as unwrap child sublayers
+ recursively, not just the top-level distributed containers.
+
+ Returns:
+ `torch.nn.Module`: The extracted model.
+ """
+ options = (torch.nn.parallel.DistributedDataParallel, torch.nn.DataParallel)
+
+ is_compiled = is_compiled_module(model)
+ has_compiled = has_compiled_regions(model)
+
+ if is_compiled:
+ compiled_model = model
+ model = model._orig_mod
+ elif has_compiled:
+ compiled_model = model
+ model = model.__dict__["_orig_mod"]
+
+ if is_deepspeed_available():
+ from deepspeed import DeepSpeedEngine
+
+ options += (DeepSpeedEngine,)
+
+ if is_torch_version(">=", FSDP_PYTORCH_VERSION) and is_torch_distributed_available():
+ from torch.distributed.fsdp.fully_sharded_data_parallel import FullyShardedDataParallel as FSDP
+
+ options += (FSDP,)
+
+ while isinstance(model, options):
+ model = model.module
+
+ if recursive:
+ # This is needed in cases such as using FSDPv2 on XLA
+ def _recursive_unwrap(module):
+ # Wrapped modules are standardly wrapped as `module`, similar to the cases earlier
+ # with DDP, DataParallel, DeepSpeed, and FSDP
+ if hasattr(module, "module"):
+ unwrapped_module = _recursive_unwrap(module.module)
+ else:
+ unwrapped_module = module
+ # Next unwrap child sublayers recursively
+ for name, child in unwrapped_module.named_children():
+ setattr(unwrapped_module, name, _recursive_unwrap(child))
+ return unwrapped_module
+
+ # Start with top-level
+ model = _recursive_unwrap(model)
+
+ if not keep_fp32_wrapper:
+ forward = model.forward
+ original_forward = model.__dict__.pop("_original_forward", None)
+ if original_forward is not None:
+ while hasattr(forward, "__wrapped__"):
+ forward = forward.__wrapped__
+ if forward == original_forward:
+ break
+ model.forward = MethodType(forward, model)
+ if getattr(model, "_converted_to_transformer_engine", False):
+ convert_model(model, to_transformer_engine=False)
+
+ if keep_torch_compile:
+ if is_compiled:
+ compiled_model._orig_mod = model
+ model = compiled_model
+ elif has_compiled:
+ compiled_model.__dict__["_orig_mod"] = model
+ model = compiled_model
+
+ return model
+
+
+def wait_for_everyone():
+ """
+ Introduces a blocking point in the script, making sure all processes have reached this point before continuing.
+
+
+
+ Make sure all processes will reach this instruction otherwise one of your processes will hang forever.
+
+
+ """
+ PartialState().wait_for_everyone()
+
+
+def clean_state_dict_for_safetensors(state_dict: dict):
+ """
+ Cleans the state dictionary from a model and removes tensor aliasing if present.
+
+ Args:
+ state_dict (`dict`):
+ The state dictionary from a model
+ """
+ ptrs = collections.defaultdict(list)
+ # When bnb serialization is used, weights in state dict can be strings
+ for name, tensor in state_dict.items():
+ if not isinstance(tensor, str):
+ ptrs[id_tensor_storage(tensor)].append(name)
+
+ # These are all pointers of tensors with shared memory
+ shared_ptrs = {ptr: names for ptr, names in ptrs.items() if len(names) > 1}
+ warn_names = set()
+ for names in shared_ptrs.values():
+ # When not all duplicates have been cleaned, we still remove those keys but put a clear warning.
+ # If the link between tensors was done at runtime then `from_pretrained` will not get
+ # the key back leading to random tensor. A proper warning will be shown
+ # during reload (if applicable), but since the file is not necessarily compatible with
+ # the config, better show a proper warning.
+ found_names = [name for name in names if name in state_dict]
+ warn_names.update(found_names[1:])
+ for name in found_names[1:]:
+ del state_dict[name]
+ if len(warn_names) > 0:
+ logger.warning(
+ f"Removed shared tensor {warn_names} while saving. This should be OK, but check by verifying that you don't receive any warning while reloading",
+ )
+ state_dict = {k: v.contiguous() if isinstance(v, torch.Tensor) else v for k, v in state_dict.items()}
+ return state_dict
+
+
+def save(obj, f, save_on_each_node: bool = False, safe_serialization: bool = False):
+ """
+ Save the data to disk. Use in place of `torch.save()`.
+
+ Args:
+ obj:
+ The data to save
+ f:
+ The file (or file-like object) to use to save the data
+ save_on_each_node (`bool`, *optional*, defaults to `False`):
+ Whether to only save on the global main process
+ safe_serialization (`bool`, *optional*, defaults to `False`):
+ Whether to save `obj` using `safetensors` or the traditional PyTorch way (that uses `pickle`).
+ """
+ # When TorchXLA is enabled, it's necessary to transfer all data to the CPU before saving.
+ # Another issue arises with `id_tensor_storage`, which treats all XLA tensors as identical.
+ # If tensors remain on XLA, calling `clean_state_dict_for_safetensors` will result in only
+ # one XLA tensor remaining.
+ if PartialState().distributed_type == DistributedType.XLA:
+ obj = xm._maybe_convert_to_cpu(obj)
+ # Check if it's a model and remove duplicates
+ if safe_serialization:
+ save_func = partial(safe_save_file, metadata={"format": "pt"})
+ if isinstance(obj, OrderedDict):
+ obj = clean_state_dict_for_safetensors(obj)
+ else:
+ save_func = torch.save
+
+ if PartialState().is_main_process and not save_on_each_node:
+ save_func(obj, f)
+ elif PartialState().is_local_main_process and save_on_each_node:
+ save_func(obj, f)
+
+
+# The following are considered "safe" globals to reconstruct various types of objects when using `weights_only=True`
+# These should be added and then removed after loading in the file
+np_core = np._core if is_numpy_available("2.0.0") else np.core
+TORCH_SAFE_GLOBALS = [
+ # numpy arrays are just numbers, not objects, so we can reconstruct them safely
+ np_core.multiarray._reconstruct,
+ np.ndarray,
+ # The following are needed for the RNG states
+ encode,
+ np.dtype,
+]
+
+if is_numpy_available("1.25.0"):
+ TORCH_SAFE_GLOBALS.append(np.dtypes.UInt32DType)
+
+
+def load(f, map_location=None, **kwargs):
+ """
+ Compatible drop-in replacement of `torch.load()` which allows for `weights_only` to be used if `torch` version is
+ 2.4.0 or higher. Otherwise will ignore the kwarg.
+
+ Will also add (and then remove) an exception for numpy arrays
+
+ Args:
+ f:
+ The file (or file-like object) to use to load the data
+ map_location:
+ a function, `torch.device`, string or a dict specifying how to remap storage locations
+ **kwargs:
+ Additional keyword arguments to pass to `torch.load()`.
+ """
+ try:
+ if is_weights_only_available():
+ old_safe_globals = torch.serialization.get_safe_globals()
+ if "weights_only" not in kwargs:
+ kwargs["weights_only"] = True
+ torch.serialization.add_safe_globals(TORCH_SAFE_GLOBALS)
+ else:
+ kwargs.pop("weights_only", None)
+ loaded_obj = torch.load(f, map_location=map_location, **kwargs)
+ finally:
+ if is_weights_only_available():
+ torch.serialization.clear_safe_globals()
+ if old_safe_globals:
+ torch.serialization.add_safe_globals(old_safe_globals)
+ return loaded_obj
+
+
+def get_pretty_name(obj):
+ """
+ Gets a pretty name from `obj`.
+ """
+ if not hasattr(obj, "__qualname__") and not hasattr(obj, "__name__"):
+ obj = getattr(obj, "__class__", obj)
+ if hasattr(obj, "__qualname__"):
+ return obj.__qualname__
+ if hasattr(obj, "__name__"):
+ return obj.__name__
+ return str(obj)
+
+
+def merge_dicts(source, destination):
+ """
+ Recursively merges two dictionaries.
+
+ Args:
+ source (`dict`): The dictionary to merge into `destination`.
+ destination (`dict`): The dictionary to merge `source` into.
+ """
+ for key, value in source.items():
+ if isinstance(value, dict):
+ node = destination.setdefault(key, {})
+ merge_dicts(value, node)
+ else:
+ destination[key] = value
+
+ return destination
+
+
+def is_port_in_use(port: Optional[int] = None) -> bool:
+ """
+ Checks if a port is in use on `localhost`. Useful for checking if multiple `accelerate launch` commands have been
+ run and need to see if the port is already in use.
+ """
+ if port is None:
+ port = 29500
+ with socket.socket(socket.AF_INET, socket.SOCK_STREAM) as s:
+ return s.connect_ex(("localhost", port)) == 0
+
+
+def get_free_port() -> int:
+ """
+ Gets a free port on `localhost`. Useful for automatic port selection when port 0 is specified in distributed
+ training scenarios.
+
+ Returns:
+ int: An available port number
+ """
+ with socket.socket(socket.AF_INET, socket.SOCK_STREAM) as s:
+ s.bind(("", 0)) # bind to port 0 for OS to assign a free port
+ return s.getsockname()[1]
+
+
+def convert_bytes(size):
+ "Converts `size` from bytes to the largest possible unit"
+ for x in ["bytes", "KB", "MB", "GB", "TB"]:
+ if size < 1024.0:
+ return f"{round(size, 2)} {x}"
+ size /= 1024.0
+
+ return f"{round(size, 2)} PB"
+
+
+def check_os_kernel():
+ """Warns if the kernel version is below the recommended minimum on Linux."""
+ # see issue #1929
+ info = platform.uname()
+ system = info.system
+ if system != "Linux":
+ return
+
+ _, version, *_ = re.split(r"(\d+\.\d+\.\d+)", info.release)
+ min_version = "5.5.0"
+ if Version(version) < Version(min_version):
+ msg = (
+ f"Detected kernel version {version}, which is below the recommended minimum of {min_version}; this can "
+ "cause the process to hang. It is recommended to upgrade the kernel to the minimum version or higher."
+ )
+ logger.warning(msg, main_process_only=True)
+
+
+def recursive_getattr(obj, attr: str):
+ """
+ Recursive `getattr`.
+
+ Args:
+ obj:
+ A class instance holding the attribute.
+ attr (`str`):
+ The attribute that is to be retrieved, e.g. 'attribute1.attribute2'.
+ """
+
+ def _getattr(obj, attr):
+ return getattr(obj, attr)
+
+ return reduce(_getattr, [obj] + attr.split("."))
+
+
+def get_module_children_bottom_up(model: torch.nn.Module, return_fqns: bool = False) -> list[torch.nn.Module]:
+ """Traverse the model in bottom-up order and return the children modules in that order.
+
+ Args:
+ model (`torch.nn.Module`): the model to get the children of
+
+ Returns:
+ `list[torch.nn.Module]`: a list of children modules of `model` in bottom-up order. The last element is the
+ `model` itself.
+ """
+ top = model if not return_fqns else ("", model)
+ stack = [top]
+ ordered_modules = []
+ while stack:
+ current_module = stack.pop()
+ if return_fqns:
+ current_module_name, current_module = current_module
+ for name, attr in current_module.named_children():
+ if isinstance(attr, torch.nn.Module):
+ if return_fqns:
+ child_name = current_module_name + "." + name if current_module_name else name
+ stack.append((child_name, attr))
+ else:
+ stack.append(attr)
+ if return_fqns:
+ ordered_modules.append((current_module_name, current_module))
+ else:
+ ordered_modules.append(current_module)
+ return ordered_modules[::-1]
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/random.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/random.py
new file mode 100644
index 0000000000000000000000000000000000000000..9dceb598cacc1c1d17b198e0a7c19789ab3b9f39
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/random.py
@@ -0,0 +1,156 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import random
+from typing import Optional, Union
+
+import numpy as np
+import torch
+
+from ..state import AcceleratorState
+from .constants import CUDA_DISTRIBUTED_TYPES
+from .dataclasses import DistributedType, RNGType
+from .imports import (
+ is_hpu_available,
+ is_mlu_available,
+ is_musa_available,
+ is_npu_available,
+ is_sdaa_available,
+ is_torch_xla_available,
+ is_xpu_available,
+)
+
+
+if is_torch_xla_available():
+ import torch_xla.core.xla_model as xm
+
+
+def set_seed(seed: int, device_specific: bool = False, deterministic: bool = False):
+ """
+ Helper function for reproducible behavior to set the seed in `random`, `numpy`, `torch`.
+
+ Args:
+ seed (`int`):
+ The seed to set.
+ device_specific (`bool`, *optional*, defaults to `False`):
+ Whether to differ the seed on each device slightly with `self.process_index`.
+ deterministic (`bool`, *optional*, defaults to `False`):
+ Whether to use deterministic algorithms where available. Can slow down training.
+ """
+ if device_specific:
+ seed += AcceleratorState().process_index
+ random.seed(seed)
+ np.random.seed(seed)
+ torch.manual_seed(seed)
+ if is_xpu_available():
+ torch.xpu.manual_seed_all(seed)
+ elif is_npu_available():
+ torch.npu.manual_seed_all(seed)
+ elif is_mlu_available():
+ torch.mlu.manual_seed_all(seed)
+ elif is_sdaa_available():
+ torch.sdaa.manual_seed_all(seed)
+ elif is_musa_available():
+ torch.musa.manual_seed_all(seed)
+ elif is_hpu_available():
+ torch.hpu.manual_seed_all(seed)
+ else:
+ torch.cuda.manual_seed_all(seed)
+ # ^^ safe to call this function even if cuda is not available
+ if is_torch_xla_available():
+ xm.set_rng_state(seed)
+
+ if deterministic:
+ torch.use_deterministic_algorithms(True)
+
+
+def synchronize_rng_state(rng_type: Optional[RNGType] = None, generator: Optional[torch.Generator] = None):
+ # Get the proper rng state
+ if rng_type == RNGType.TORCH:
+ rng_state = torch.get_rng_state()
+ elif rng_type == RNGType.CUDA:
+ rng_state = torch.cuda.get_rng_state()
+ elif rng_type == RNGType.XLA:
+ assert is_torch_xla_available(), "Can't synchronize XLA seeds as torch_xla is unavailable."
+ rng_state = torch.tensor(xm.get_rng_state())
+ elif rng_type == RNGType.NPU:
+ assert is_npu_available(), "Can't synchronize NPU seeds on an environment without NPUs."
+ rng_state = torch.npu.get_rng_state()
+ elif rng_type == RNGType.MLU:
+ assert is_mlu_available(), "Can't synchronize MLU seeds on an environment without MLUs."
+ rng_state = torch.mlu.get_rng_state()
+ elif rng_type == RNGType.SDAA:
+ assert is_sdaa_available(), "Can't synchronize SDAA seeds on an environment without SDAAs."
+ rng_state = torch.sdaa.get_rng_state()
+ elif rng_type == RNGType.MUSA:
+ assert is_musa_available(), "Can't synchronize MUSA seeds on an environment without MUSAs."
+ rng_state = torch.musa.get_rng_state()
+ elif rng_type == RNGType.XPU:
+ assert is_xpu_available(), "Can't synchronize XPU seeds on an environment without XPUs."
+ rng_state = torch.xpu.get_rng_state()
+ elif rng_type == RNGType.HPU:
+ assert is_hpu_available(), "Can't synchronize HPU seeds on an environment without HPUs."
+ rng_state = torch.hpu.get_rng_state()
+ elif rng_type == RNGType.GENERATOR:
+ assert generator is not None, "Need a generator to synchronize its seed."
+ rng_state = generator.get_state()
+
+ # Broadcast the rng state from device 0 to other devices
+ state = AcceleratorState()
+ if state.distributed_type == DistributedType.XLA:
+ rng_state = rng_state.to(xm.xla_device())
+ xm.collective_broadcast([rng_state])
+ xm.mark_step()
+ rng_state = rng_state.cpu()
+ elif (
+ state.distributed_type in CUDA_DISTRIBUTED_TYPES
+ or state.distributed_type == DistributedType.MULTI_MLU
+ or state.distributed_type == DistributedType.MULTI_SDAA
+ or state.distributed_type == DistributedType.MULTI_MUSA
+ or state.distributed_type == DistributedType.MULTI_NPU
+ or state.distributed_type == DistributedType.MULTI_XPU
+ or state.distributed_type == DistributedType.MULTI_HPU
+ ):
+ rng_state = rng_state.to(state.device)
+ torch.distributed.broadcast(rng_state, 0)
+ rng_state = rng_state.cpu()
+ elif state.distributed_type == DistributedType.MULTI_CPU:
+ torch.distributed.broadcast(rng_state, 0)
+
+ # Set the broadcast rng state
+ if rng_type == RNGType.TORCH:
+ torch.set_rng_state(rng_state)
+ elif rng_type == RNGType.CUDA:
+ torch.cuda.set_rng_state(rng_state)
+ elif rng_type == RNGType.NPU:
+ torch.npu.set_rng_state(rng_state)
+ elif rng_type == RNGType.MLU:
+ torch.mlu.set_rng_state(rng_state)
+ elif rng_type == RNGType.SDAA:
+ torch.sdaa.set_rng_state(rng_state)
+ elif rng_type == RNGType.MUSA:
+ torch.musa.set_rng_state(rng_state)
+ elif rng_type == RNGType.XPU:
+ torch.xpu.set_rng_state(rng_state)
+ elif rng_state == RNGType.HPU:
+ torch.hpu.set_rng_state(rng_state)
+ elif rng_type == RNGType.XLA:
+ xm.set_rng_state(rng_state.item())
+ elif rng_type == RNGType.GENERATOR:
+ generator.set_state(rng_state)
+
+
+def synchronize_rng_states(rng_types: list[Union[str, RNGType]], generator: Optional[torch.Generator] = None):
+ for rng_type in rng_types:
+ synchronize_rng_state(RNGType(rng_type), generator=generator)
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/rich.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/rich.py
new file mode 100644
index 0000000000000000000000000000000000000000..2d48661b7fcef92ef1168b74cc275c6d3ccc67a1
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/rich.py
@@ -0,0 +1,24 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from .imports import is_rich_available
+
+
+if is_rich_available():
+ from rich.traceback import install
+
+ install(show_locals=False)
+
+else:
+ raise ModuleNotFoundError("To use the rich extension, install rich with `pip install rich`")
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/torch_xla.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/torch_xla.py
new file mode 100644
index 0000000000000000000000000000000000000000..140133926c2f88d39c70f5a9f46a08f88bed36da
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/torch_xla.py
@@ -0,0 +1,51 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import importlib.metadata
+import subprocess
+import sys
+
+
+def install_xla(upgrade: bool = False):
+ """
+ Helper function to install appropriate xla wheels based on the `torch` version in Google Colaboratory.
+
+ Args:
+ upgrade (`bool`, *optional*, defaults to `False`):
+ Whether to upgrade `torch` and install the latest `torch_xla` wheels.
+
+ Example:
+
+ ```python
+ >>> from accelerate.utils import install_xla
+
+ >>> install_xla(upgrade=True)
+ ```
+ """
+ in_colab = False
+ if "IPython" in sys.modules:
+ in_colab = "google.colab" in str(sys.modules["IPython"].get_ipython())
+
+ if in_colab:
+ if upgrade:
+ torch_install_cmd = ["pip", "install", "-U", "torch"]
+ subprocess.run(torch_install_cmd, check=True)
+ # get the current version of torch
+ torch_version = importlib.metadata.version("torch")
+ torch_version_trunc = torch_version[: torch_version.rindex(".")]
+ xla_wheel = f"https://storage.googleapis.com/tpu-pytorch/wheels/colab/torch_xla-{torch_version_trunc}-cp37-cp37m-linux_x86_64.whl"
+ xla_install_cmd = ["pip", "install", xla_wheel]
+ subprocess.run(xla_install_cmd, check=True)
+ else:
+ raise RuntimeError("`install_xla` utility works only on google colab.")
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/tqdm.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/tqdm.py
new file mode 100644
index 0000000000000000000000000000000000000000..2d4873c1573eb2ee7392162f440a76d4f07cd8ce
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/tqdm.py
@@ -0,0 +1,43 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+
+from .imports import is_tqdm_available
+
+
+if is_tqdm_available():
+ from tqdm.auto import tqdm as _tqdm
+
+from ..state import PartialState
+
+
+def tqdm(*args, main_process_only: bool = True, **kwargs):
+ """
+ Wrapper around `tqdm.tqdm` that optionally displays only on the main process.
+
+ Args:
+ main_process_only (`bool`, *optional*):
+ Whether to display the progress bar only on the main process
+ """
+ if not is_tqdm_available():
+ raise ImportError("Accelerate's `tqdm` module requires `tqdm` to be installed. Please run `pip install tqdm`.")
+ if len(args) > 0 and isinstance(args[0], bool):
+ raise ValueError(
+ "Passing `True` or `False` as the first argument to Accelerate's `tqdm` wrapper is unsupported. "
+ "Please use the `main_process_only` keyword argument instead."
+ )
+ disable = kwargs.pop("disable", False)
+ if main_process_only and not disable:
+ disable = PartialState().local_process_index != 0
+ return _tqdm(*args, **kwargs, disable=disable)
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/transformer_engine.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/transformer_engine.py
new file mode 100644
index 0000000000000000000000000000000000000000..6a950d131ddcb1575a2cccd7937ed25bf762663e
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/transformer_engine.py
@@ -0,0 +1,186 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from types import MethodType
+
+import torch.nn as nn
+
+from .imports import is_hpu_available, is_transformer_engine_available
+from .operations import GatheredParameters
+
+
+# Do not import `transformer_engine` at package level to avoid potential issues
+
+
+def convert_model(model, to_transformer_engine=True, _convert_linear=True, _convert_ln=True):
+ """
+ Recursively converts the linear and layernorm layers of a model to their `transformers_engine` counterpart.
+ """
+ if not is_transformer_engine_available():
+ raise ImportError("Using `convert_model` requires transformer_engine to be installed.")
+
+ if is_hpu_available():
+ import intel_transformer_engine as te
+
+ if not hasattr(te, "LayerNorm"):
+ # HPU does not have a LayerNorm implementation in TE
+ te.LayerNorm = nn.LayerNorm
+ else:
+ import transformer_engine.pytorch as te
+
+ for name, module in model.named_children():
+ if isinstance(module, nn.Linear) and to_transformer_engine and _convert_linear:
+ has_bias = module.bias is not None
+ params_to_gather = [module.weight]
+ if has_bias:
+ params_to_gather.append(module.bias)
+
+ with GatheredParameters(params_to_gather, modifier_rank=0):
+ if any(p % 16 != 0 for p in module.weight.shape):
+ return
+ te_module = te.Linear(
+ module.in_features, module.out_features, bias=has_bias, params_dtype=module.weight.dtype
+ )
+ te_module.weight.copy_(module.weight)
+ if has_bias:
+ te_module.bias.copy_(module.bias)
+
+ setattr(model, name, te_module)
+ # Note: @xrsrke (Phuc) found that te.LayerNorm doesn't have any real memory savings or speedups over nn.LayerNorm
+ elif isinstance(module, nn.LayerNorm) and to_transformer_engine and _convert_ln:
+ with GatheredParameters([module.weight, module.bias], modifier_rank=0):
+ has_bias = module.bias is not None
+ te_module = te.LayerNorm(module.normalized_shape[0], eps=module.eps, params_dtype=module.weight.dtype)
+ te_module.weight.copy_(module.weight)
+ if has_bias:
+ te_module.bias.copy_(module.bias)
+
+ setattr(model, name, te_module)
+ elif isinstance(module, te.Linear) and not to_transformer_engine and _convert_linear:
+ has_bias = module.bias is not None
+ new_module = nn.Linear(
+ module.in_features, module.out_features, bias=has_bias, params_dtype=module.weight.dtype
+ )
+ new_module.weight.copy_(module.weight)
+ if has_bias:
+ new_module.bias.copy_(module.bias)
+
+ setattr(model, name, new_module)
+ elif isinstance(module, te.LayerNorm) and not to_transformer_engine and _convert_ln:
+ new_module = nn.LayerNorm(module.normalized_shape[0], eps=module.eps, params_dtype=module.weight.dtype)
+ new_module.weight.copy_(module.weight)
+ new_module.bias.copy_(module.bias)
+
+ setattr(model, name, new_module)
+ else:
+ convert_model(
+ module,
+ to_transformer_engine=to_transformer_engine,
+ _convert_linear=_convert_linear,
+ _convert_ln=_convert_ln,
+ )
+
+
+def has_transformer_engine_layers(model):
+ """
+ Returns whether a given model has some `transformer_engine` layer or not.
+ """
+ if not is_transformer_engine_available():
+ raise ImportError("Using `has_transformer_engine_layers` requires transformer_engine to be installed.")
+
+ if is_hpu_available():
+ import intel_transformer_engine as te
+
+ module_cls_to_check = te.Linear
+ else:
+ import transformer_engine.pytorch as te
+
+ module_cls_to_check = (te.LayerNorm, te.Linear, te.TransformerLayer)
+
+ for m in model.modules():
+ if isinstance(m, module_cls_to_check):
+ return True
+
+ return False
+
+
+def contextual_fp8_autocast(model_forward, fp8_recipe, use_during_eval=False):
+ """
+ Wrapper for a model's forward method to apply FP8 autocast. Is context aware, meaning that by default it will
+ disable FP8 autocast during eval mode, which is generally better for more accurate metrics.
+ """
+ if not is_transformer_engine_available():
+ raise ImportError("Using `contextual_fp8_autocast` requires transformer_engine to be installed.")
+
+ if is_hpu_available():
+ from intel_transformer_engine import fp8_autocast
+ else:
+ from transformer_engine.pytorch import fp8_autocast
+
+ def forward(self, *args, **kwargs):
+ enabled = use_during_eval or self.training
+ with fp8_autocast(enabled=enabled, fp8_recipe=fp8_recipe):
+ return model_forward(*args, **kwargs)
+
+ # To act like a decorator so that it can be popped when doing `extract_model_from_parallel`
+ forward.__wrapped__ = model_forward
+
+ return forward
+
+
+def apply_fp8_autowrap(model, fp8_recipe_handler):
+ """
+ Applies FP8 context manager to the model's forward method
+ """
+ if not is_transformer_engine_available():
+ raise ImportError("Using `apply_fp8_autowrap` requires transformer_engine to be installed.")
+
+ if is_hpu_available():
+ import intel_transformer_engine.recipe as te_recipe
+
+ is_fp8_block_scaling_available = False
+ message = "MXFP8 block scaling is not available on HPU."
+
+ else:
+ import transformer_engine.common.recipe as te_recipe
+ import transformer_engine.pytorch as te
+
+ is_fp8_block_scaling_available, message = te.fp8.check_mxfp8_support()
+
+ kwargs = fp8_recipe_handler.to_kwargs() if fp8_recipe_handler is not None else {}
+ if "fp8_format" in kwargs:
+ kwargs["fp8_format"] = getattr(te_recipe.Format, kwargs["fp8_format"])
+ use_during_eval = kwargs.pop("use_autocast_during_eval", False)
+ use_mxfp8_block_scaling = kwargs.pop("use_mxfp8_block_scaling", False)
+
+ if use_mxfp8_block_scaling and not is_fp8_block_scaling_available:
+ raise ValueError(f"MXFP8 block scaling is not available: {message}")
+
+ if use_mxfp8_block_scaling:
+ if "amax_compute_algo" in kwargs:
+ raise ValueError("`amax_compute_algo` is not supported for MXFP8 block scaling.")
+ if "amax_history_len" in kwargs:
+ raise ValueError("`amax_history_len` is not supported for MXFP8 block scaling.")
+ fp8_recipe = te_recipe.MXFP8BlockScaling(**kwargs)
+ else:
+ fp8_recipe = te_recipe.DelayedScaling(**kwargs)
+
+ new_forward = contextual_fp8_autocast(model.forward, fp8_recipe, use_during_eval)
+
+ if hasattr(model.forward, "__func__"):
+ model.forward = MethodType(new_forward, model)
+ else:
+ model.forward = new_forward
+
+ return model
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/versions.py b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/versions.py
new file mode 100644
index 0000000000000000000000000000000000000000..985c918f0e057bacc70c372f6906071bb73db577
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/src/accelerate/utils/versions.py
@@ -0,0 +1,56 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import importlib.metadata
+from typing import Union
+
+from packaging.version import Version, parse
+
+from .constants import STR_OPERATION_TO_FUNC
+
+
+torch_version = parse(importlib.metadata.version("torch"))
+
+
+def compare_versions(library_or_version: Union[str, Version], operation: str, requirement_version: str):
+ """
+ Compares a library version to some requirement using a given operation.
+
+ Args:
+ library_or_version (`str` or `packaging.version.Version`):
+ A library name or a version to check.
+ operation (`str`):
+ A string representation of an operator, such as `">"` or `"<="`.
+ requirement_version (`str`):
+ The version to compare the library version against
+ """
+ if operation not in STR_OPERATION_TO_FUNC.keys():
+ raise ValueError(f"`operation` must be one of {list(STR_OPERATION_TO_FUNC.keys())}, received {operation}")
+ operation = STR_OPERATION_TO_FUNC[operation]
+ if isinstance(library_or_version, str):
+ library_or_version = parse(importlib.metadata.version(library_or_version))
+ return operation(library_or_version, parse(requirement_version))
+
+
+def is_torch_version(operation: str, version: str):
+ """
+ Compares the current PyTorch version to a given reference with an operation.
+
+ Args:
+ operation (`str`):
+ A string representation of an operator, such as `">"` or `"<="`
+ version (`str`):
+ A string version of PyTorch
+ """
+ return compare_versions(torch_version, operation, version)
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/utils/log_reports.py b/tasks/tasksmith-3d762a2acfee/environment/source/utils/log_reports.py
new file mode 100644
index 0000000000000000000000000000000000000000..6775cb76e1738c48f9e03ef03bec1d5fc5970659
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/utils/log_reports.py
@@ -0,0 +1,177 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import json
+import os
+from datetime import date
+from pathlib import Path
+
+from tabulate import DataRow, TableFormat, tabulate
+
+
+hf_table_format = TableFormat(
+ lineabove=None,
+ linebelowheader=None,
+ linebetweenrows=None,
+ linebelow=None,
+ headerrow=DataRow("", "|", "|"),
+ datarow=DataRow("", "|", "|"),
+ padding=1,
+ with_header_hide=None,
+)
+
+
+failed = []
+group_info = []
+
+no_error_payload = {"type": "section", "text": {"type": "plain_text", "text": "No failed tests! 🤗", "emoji": True}}
+
+payload = [
+ {
+ "type": "header",
+ "text": {
+ "type": "plain_text",
+ "text": f"🤗 Accelerate nightly {os.environ.get('TEST_TYPE', '')} test results",
+ "emoji": True,
+ },
+ }
+]
+
+total_num_failed = 0
+for log in Path().glob("*.log"):
+ section_num_failed = 0
+ with open(log) as f:
+ for line in f:
+ line = json.loads(line)
+ if line.get("nodeid", "") != "":
+ test = line["nodeid"]
+ if line.get("duration", None) is not None:
+ duration = f"{line['duration']:.4f}"
+ if line.get("outcome", "") == "failed":
+ section_num_failed += 1
+ failed.append([test, duration, log.name.split("_")[0]])
+ total_num_failed += 1
+ group_info.append([str(log), section_num_failed, failed])
+ failed = []
+ log.unlink()
+
+message = ""
+all_files2failed = []
+if total_num_failed > 0:
+ for name, num_failed, failed_tests in group_info:
+ if num_failed > 0:
+ if num_failed == 1:
+ message += f"*{name[1:]}: {num_failed} failed test*\n"
+ else:
+ message += f"*{name[1:]}: {num_failed} failed tests*\n"
+ failed_table = []
+ files2failed = {}
+ for test in failed_tests:
+ data = test[0].split("::")
+ data[0] = data[0].split("/")[-1]
+ if data[0] not in files2failed:
+ files2failed[data[0]] = [data[1:]]
+ else:
+ files2failed[data[0]] += [data[1:]]
+ failed_table.append(data)
+
+ files = [test[0] for test in failed_table]
+ individual_files = list(set(files))
+ # Count number of instances in failed_tests
+ table = []
+ for file in individual_files:
+ table.append([file, len(files2failed[file])])
+
+ failed_table = tabulate(
+ table,
+ headers=["Test Location", "Num Failed"],
+ tablefmt=hf_table_format,
+ stralign="right",
+ )
+ message += f"\n```\n{failed_table}\n```"
+ all_files2failed.append(files2failed)
+ if len(message) > 3000:
+ err = "Too many failed tests, please see the full report in the Action results."
+ offset = len(err) + 10
+ message = message[: 3000 - offset] + f"\n...\n```\n{err}"
+ print(f"### {message}")
+else:
+ message = "No failed tests! 🤗"
+ print(f"## {message}")
+ payload.append(no_error_payload)
+
+if os.environ.get("TEST_TYPE", "") != "":
+ from slack_sdk import WebClient
+
+ client = WebClient(token=os.environ["SLACK_API_TOKEN"])
+ if message != "No failed tests! 🤗":
+ md_report = {
+ "type": "section",
+ "text": {
+ "type": "mrkdwn",
+ "text": message,
+ },
+ }
+ payload.append(md_report)
+ action_button = {
+ "type": "section",
+ "text": {
+ "type": "mrkdwn",
+ "text": "*For more details:*",
+ },
+ "accessory": {
+ "type": "button",
+ "text": {
+ "type": "plain_text",
+ "text": "Check Action results",
+ "emoji": True,
+ },
+ "url": f"https://github.com/{os.environ['GITHUB_REPOSITORY']}/actions/runs/{os.environ['GITHUB_RUN_ID']}",
+ },
+ }
+ payload.append(action_button)
+ date_report = {
+ "type": "context",
+ "elements": [
+ {
+ "type": "plain_text",
+ "text": f"Nightly {os.environ.get('TEST_TYPE')} test results for {date.today()}",
+ }
+ ],
+ }
+ payload.append(date_report)
+ response = client.chat_postMessage(channel="#accelerate-ci-daily", text=message, blocks=payload)
+ ts = response.data["ts"]
+ for failed_file in all_files2failed:
+ for test_location, test_failures in failed_file.items():
+ # Keep only the first instance of the test name
+ test_class = ""
+ for i, row in enumerate(test_failures):
+ if row[0] != test_class:
+ test_class = row[0]
+ else:
+ test_failures[i][0] = ""
+
+ payload = {
+ "type": "section",
+ "text": {
+ "type": "mrkdwn",
+ "text": f"Test location: {test_location}\n```\n{tabulate(test_failures, headers=['Class', 'Test'], tablefmt=hf_table_format, stralign='right')}\n```",
+ },
+ }
+
+ client.chat_postMessage(
+ channel="#accelerate-ci-daily",
+ thread_ts=ts,
+ blocks=[payload],
+ )
diff --git a/tasks/tasksmith-3d762a2acfee/environment/source/utils/stale.py b/tasks/tasksmith-3d762a2acfee/environment/source/utils/stale.py
new file mode 100644
index 0000000000000000000000000000000000000000..24333fed4c76b34cf895f30a253a9a7042f9d324
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/environment/source/utils/stale.py
@@ -0,0 +1,69 @@
+# Copyright 2022 The HuggingFace Team, the AllenNLP library authors. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Script to close stale issue. Taken in part from the AllenNLP repository.
+https://github.com/allenai/allennlp.
+"""
+
+import os
+from datetime import datetime as dt
+from datetime import timezone
+
+from github import Github
+
+
+LABELS_TO_EXEMPT = [
+ "good first issue",
+ "feature request",
+ "wip",
+]
+
+
+def main():
+ g = Github(os.environ["GITHUB_TOKEN"])
+ repo = g.get_repo("huggingface/accelerate")
+ open_issues = repo.get_issues(state="open")
+
+ for issue in open_issues:
+ comments = sorted([comment for comment in issue.get_comments()], key=lambda i: i.created_at, reverse=True)
+ last_comment = comments[0] if len(comments) > 0 else None
+ current_time = dt.now(timezone.utc)
+ days_since_updated = (current_time - issue.updated_at).days
+ days_since_creation = (current_time - issue.created_at).days
+ if (
+ last_comment is not None
+ and last_comment.user.login == "github-actions[bot]"
+ and days_since_updated > 7
+ and days_since_creation >= 30
+ and not any(label.name.lower() in LABELS_TO_EXEMPT for label in issue.get_labels())
+ ):
+ # Close issue since it has been 7 days of inactivity since bot mention.
+ issue.edit(state="closed")
+ elif (
+ days_since_updated > 23
+ and days_since_creation >= 30
+ and not any(label.name.lower() in LABELS_TO_EXEMPT for label in issue.get_labels())
+ ):
+ # Add stale comment
+ issue.create_comment(
+ "This issue has been automatically marked as stale because it has not had "
+ "recent activity. If you think this still needs to be addressed "
+ "please comment on this thread.\n\nPlease note that issues that do not follow the "
+ "[contributing guidelines](https://github.com/huggingface/accelerate/blob/main/CONTRIBUTING.md) "
+ "are likely to be ignored."
+ )
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/instruction.md b/tasks/tasksmith-3d762a2acfee/instruction.md
new file mode 100644
index 0000000000000000000000000000000000000000..a87f279e1fd94c140cf53890e0c375200a29aa43
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/instruction.md
@@ -0,0 +1,16 @@
+The `concatenate` function in `accelerate.utils.operations` recursively concatenates tensors held in nested lists, tuples, or dicts. Fix it so that when the input collection has exactly one element and that element is not a `torch.Tensor`, list, tuple, or Mapping, the element is returned as-is instead of raising `TypeError`.
+
+Expected behaviour after the fix:
+
+```python
+concatenate(["hello"]) # → "hello"
+concatenate([True]) # → True
+concatenate([42]) # → 42
+concatenate(["a", "b"]) # → raises TypeError (multiple non-tensor items)
+concatenate([torch.zeros(2, 3), torch.ones(2, 3)]) # → tensor shape (4, 3)
+concatenate([{"t": torch.zeros(2,3), "s": "val"}]) # → {"t": tensor(2,3), "s": "val"}
+```
+
+All existing tensor-concatenation paths (plain tensors, nested lists/tuples, dicts, custom `dim`) must continue to work unchanged. Passing multiple batches with non-tensor leaf values must still raise `TypeError`.
+
+Work in `/workspace`. Submit your fix in the existing Python source files under `src/accelerate/utils/operations.py`. Preserve the other public behavior. The environment is offline; dependencies are preinstalled. Grading runs the relevant repository tests in a fresh environment, using your submitted source files.
diff --git a/tasks/tasksmith-3d762a2acfee/solution/reference/src/accelerate/utils/operations.py b/tasks/tasksmith-3d762a2acfee/solution/reference/src/accelerate/utils/operations.py
new file mode 100644
index 0000000000000000000000000000000000000000..ceec9b457fe35cf146ffe3c65c73a4b2a8fb202a
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/solution/reference/src/accelerate/utils/operations.py
@@ -0,0 +1,871 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+A set of basic tensor ops compatible with tpu, gpu, and multigpu
+"""
+
+import pickle
+import warnings
+from collections.abc import Mapping
+from contextlib import contextmanager, nullcontext
+from functools import update_wrapper, wraps
+from typing import Any
+
+import torch
+
+from ..state import AcceleratorState, PartialState
+from .constants import TORCH_DISTRIBUTED_OPERATION_TYPES
+from .dataclasses import DistributedType, TensorInformation
+from .imports import (
+ is_npu_available,
+ is_torch_distributed_available,
+ is_torch_xla_available,
+)
+from .versions import is_torch_version
+
+
+if is_torch_xla_available():
+ import torch_xla.core.xla_model as xm
+
+if is_torch_distributed_available():
+ from torch.distributed import ReduceOp
+
+
+def is_torch_tensor(tensor):
+ return isinstance(tensor, torch.Tensor)
+
+
+def is_torch_xpu_tensor(tensor):
+ return isinstance(
+ tensor,
+ torch.xpu.FloatTensor,
+ torch.xpu.ByteTensor,
+ torch.xpu.IntTensor,
+ torch.xpu.LongTensor,
+ torch.xpu.HalfTensor,
+ torch.xpu.DoubleTensor,
+ torch.xpu.BFloat16Tensor,
+ )
+
+
+def is_tensor_information(tensor_info):
+ return isinstance(tensor_info, TensorInformation)
+
+
+def is_namedtuple(data):
+ """
+ Checks if `data` is a `namedtuple` or not. Can have false positives, but only if a user is trying to mimic a
+ `namedtuple` perfectly.
+ """
+ return isinstance(data, tuple) and hasattr(data, "_asdict") and hasattr(data, "_fields")
+
+
+def honor_type(obj, generator):
+ """
+ Cast a generator to the same type as obj (list, tuple, or namedtuple)
+ """
+ # Some objects may not be able to instantiate from a generator directly
+ if is_namedtuple(obj):
+ return type(obj)(*list(generator))
+ else:
+ return type(obj)(generator)
+
+
+def recursively_apply(func, data, *args, test_type=is_torch_tensor, error_on_other_type=False, **kwargs):
+ """
+ Recursively apply a function on a data structure that is a nested list/tuple/dictionary of a given base type.
+
+ Args:
+ func (`callable`):
+ The function to recursively apply.
+ data (nested list/tuple/dictionary of `main_type`):
+ The data on which to apply `func`
+ *args:
+ Positional arguments that will be passed to `func` when applied on the unpacked data.
+ main_type (`type`, *optional*, defaults to `torch.Tensor`):
+ The base type of the objects to which apply `func`.
+ error_on_other_type (`bool`, *optional*, defaults to `False`):
+ Whether to return an error or not if after unpacking `data`, we get on an object that is not of type
+ `main_type`. If `False`, the function will leave objects of types different than `main_type` unchanged.
+ **kwargs (additional keyword arguments, *optional*):
+ Keyword arguments that will be passed to `func` when applied on the unpacked data.
+
+ Returns:
+ The same data structure as `data` with `func` applied to every object of type `main_type`.
+ """
+ if isinstance(data, (tuple, list)):
+ return honor_type(
+ data,
+ (
+ recursively_apply(
+ func, o, *args, test_type=test_type, error_on_other_type=error_on_other_type, **kwargs
+ )
+ for o in data
+ ),
+ )
+ elif isinstance(data, Mapping):
+ return type(data)(
+ {
+ k: recursively_apply(
+ func, v, *args, test_type=test_type, error_on_other_type=error_on_other_type, **kwargs
+ )
+ for k, v in data.items()
+ }
+ )
+ elif test_type(data):
+ return func(data, *args, **kwargs)
+ elif error_on_other_type:
+ raise TypeError(
+ f"Unsupported types ({type(data)}) passed to `{func.__name__}`. Only nested list/tuple/dicts of "
+ f"objects that are valid for `{test_type.__name__}` should be passed."
+ )
+ return data
+
+
+def send_to_device(tensor, device, non_blocking=False, skip_keys=None):
+ """
+ Recursively sends the elements in a nested list/tuple/dictionary of tensors to a given device.
+
+ Args:
+ tensor (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to send to a given device.
+ device (`torch.device`):
+ The device to send the data to.
+
+ Returns:
+ The same data structure as `tensor` with all tensors sent to the proper device.
+ """
+ if is_torch_tensor(tensor) or hasattr(tensor, "to"):
+ # `torch.Tensor.to("npu")` could not find context when called for the first time (see this [issue](https://gitee.com/ascend/pytorch/issues/I8KECW?from=project-issue)).
+ if device == "npu":
+ device = "npu:0"
+ try:
+ return tensor.to(device, non_blocking=non_blocking)
+ except TypeError: # .to() doesn't accept non_blocking as kwarg
+ return tensor.to(device)
+ except AssertionError as error:
+ # `torch.Tensor.to()` is not supported by `torch_npu` (see this [issue](https://github.com/Ascend/pytorch/issues/16)).
+ # This call is inside the try-block since is_npu_available is not supported by torch.compile.
+ if is_npu_available():
+ if isinstance(device, int):
+ device = f"npu:{device}"
+ else:
+ raise error
+ try:
+ return tensor.to(device, non_blocking=non_blocking)
+ except TypeError: # .to() doesn't accept non_blocking as kwarg
+ return tensor.to(device)
+ elif isinstance(tensor, (tuple, list)):
+ return honor_type(
+ tensor, (send_to_device(t, device, non_blocking=non_blocking, skip_keys=skip_keys) for t in tensor)
+ )
+ elif isinstance(tensor, Mapping):
+ if isinstance(skip_keys, str):
+ skip_keys = [skip_keys]
+ elif skip_keys is None:
+ skip_keys = []
+ return type(tensor)(
+ {
+ k: t if k in skip_keys else send_to_device(t, device, non_blocking=non_blocking, skip_keys=skip_keys)
+ for k, t in tensor.items()
+ }
+ )
+ else:
+ return tensor
+
+
+def get_data_structure(data):
+ """
+ Recursively gathers the information needed to rebuild a nested list/tuple/dictionary of tensors.
+
+ Args:
+ data (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to send to analyze.
+
+ Returns:
+ The same data structure as `data` with [`~utils.TensorInformation`] instead of tensors.
+ """
+
+ def _get_data_structure(tensor):
+ return TensorInformation(shape=tensor.shape, dtype=tensor.dtype)
+
+ return recursively_apply(_get_data_structure, data)
+
+
+def get_shape(data):
+ """
+ Recursively gathers the shape of a nested list/tuple/dictionary of tensors as a list.
+
+ Args:
+ data (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to send to analyze.
+
+ Returns:
+ The same data structure as `data` with lists of tensor shapes instead of tensors.
+ """
+
+ def _get_shape(tensor):
+ return list(tensor.shape)
+
+ return recursively_apply(_get_shape, data)
+
+
+def initialize_tensors(data_structure):
+ """
+ Recursively initializes tensors from a nested list/tuple/dictionary of [`~utils.TensorInformation`].
+
+ Returns:
+ The same data structure as `data` with tensors instead of [`~utils.TensorInformation`].
+ """
+
+ def _initialize_tensor(tensor_info):
+ return torch.empty(*tensor_info.shape, dtype=tensor_info.dtype)
+
+ return recursively_apply(_initialize_tensor, data_structure, test_type=is_tensor_information)
+
+
+def find_batch_size(data):
+ """
+ Recursively finds the batch size in a nested list/tuple/dictionary of lists of tensors.
+
+ Args:
+ data (nested list/tuple/dictionary of `torch.Tensor`): The data from which to find the batch size.
+
+ Returns:
+ `int`: The batch size.
+ """
+ if isinstance(data, (tuple, list, Mapping)) and (len(data) == 0):
+ raise ValueError(f"Cannot find the batch size from empty {type(data)}.")
+
+ if isinstance(data, (tuple, list)):
+ return find_batch_size(data[0])
+ elif isinstance(data, Mapping):
+ for k in data.keys():
+ return find_batch_size(data[k])
+ elif not isinstance(data, torch.Tensor):
+ raise TypeError(f"Can only find the batch size of tensors but got {type(data)}.")
+ return data.shape[0]
+
+
+def ignorant_find_batch_size(data):
+ """
+ Same as [`utils.operations.find_batch_size`] except will ignore if `ValueError` and `TypeErrors` are raised
+
+ Args:
+ data (nested list/tuple/dictionary of `torch.Tensor`): The data from which to find the batch size.
+
+ Returns:
+ `int`: The batch size.
+ """
+ try:
+ return find_batch_size(data)
+ except (ValueError, TypeError):
+ pass
+ return None
+
+
+def listify(data):
+ """
+ Recursively finds tensors in a nested list/tuple/dictionary and converts them to a list of numbers.
+
+ Args:
+ data (nested list/tuple/dictionary of `torch.Tensor`): The data from which to convert to regular numbers.
+
+ Returns:
+ The same data structure as `data` with lists of numbers instead of `torch.Tensor`.
+ """
+
+ def _convert_to_list(tensor):
+ tensor = tensor.detach().cpu()
+ if tensor.dtype == torch.bfloat16:
+ # As of Numpy 1.21.4, NumPy does not support bfloat16 (see
+ # https://github.com/numpy/numpy/blob/a47ecdea856986cd60eabbd53265c2ca5916ad5d/doc/source/user/basics.types.rst ).
+ # Until Numpy adds bfloat16, we must convert float32.
+ tensor = tensor.to(torch.float32)
+ return tensor.tolist()
+
+ return recursively_apply(_convert_to_list, data)
+
+
+def _tpu_gather(tensor):
+ def _tpu_gather_one(tensor):
+ if tensor.ndim == 0:
+ tensor = tensor.clone()[None]
+
+ # Can only gather contiguous tensors
+ if not tensor.is_contiguous():
+ tensor = tensor.contiguous()
+ return xm.all_gather(tensor)
+
+ res = recursively_apply(_tpu_gather_one, tensor, error_on_other_type=True)
+ xm.mark_step()
+ return res
+
+
+def _gpu_gather(tensor):
+ state = PartialState()
+ gather_op = torch.distributed.all_gather_into_tensor
+
+ # NOTE: need manually synchronize to workaourd a INT64 collectives bug in oneCCL before torch 2.9.0
+ if state.device.type == "xpu" and is_torch_version("<=", "2.8"):
+ torch.xpu.synchronize()
+
+ def _gpu_gather_one(tensor):
+ if tensor.ndim == 0:
+ tensor = tensor.clone()[None]
+
+ # Can only gather contiguous tensors
+ if not tensor.is_contiguous():
+ tensor = tensor.contiguous()
+
+ if state.backend is not None and state.backend != "gloo":
+ # We use `empty` as `all_gather_into_tensor` slightly
+ # differs from `all_gather` for better efficiency,
+ # and we rely on the number of items in the tensor
+ # rather than its direct shape
+ output_tensors = torch.empty(
+ state.num_processes * tensor.numel(),
+ dtype=tensor.dtype,
+ device=state.device,
+ )
+ gather_op(output_tensors, tensor)
+ return output_tensors.view(-1, *tensor.size()[1:])
+ else:
+ # a backend of `None` is always CPU
+ # also gloo does not support `all_gather_into_tensor`,
+ # which will result in a larger memory overhead for the op
+ output_tensors = [torch.empty_like(tensor) for _ in range(state.num_processes)]
+ torch.distributed.all_gather(output_tensors, tensor)
+ return torch.cat(output_tensors, dim=0)
+
+ return recursively_apply(_gpu_gather_one, tensor, error_on_other_type=True)
+
+
+class DistributedOperationException(Exception):
+ """
+ An exception class for distributed operations. Raised if the operation cannot be performed due to the shape of the
+ tensors.
+ """
+
+ pass
+
+
+def verify_operation(function):
+ """
+ Verifies that `tensor` is the same shape across all processes. Only ran if `PartialState().debug` is `True`.
+ """
+
+ @wraps(function)
+ def wrapper(*args, **kwargs):
+ if PartialState().distributed_type == DistributedType.NO or not PartialState().debug:
+ return function(*args, **kwargs)
+ operation = f"{function.__module__}.{function.__name__}"
+ if "tensor" in kwargs:
+ tensor = kwargs["tensor"]
+ else:
+ tensor = args[0]
+ if PartialState().device.type != find_device(tensor).type:
+ raise DistributedOperationException(
+ f"One or more of the tensors passed to {operation} were not on the {tensor.device.type} while the `Accelerator` is configured for {PartialState().device.type}. "
+ f"Please move it to the {PartialState().device.type} before calling {operation}."
+ )
+ shapes = get_shape(tensor)
+ output = gather_object([shapes])
+ if output[0] is not None:
+ are_same = output.count(output[0]) == len(output)
+ if not are_same:
+ process_shape_str = "\n - ".join([f"Process {i}: {shape}" for i, shape in enumerate(output)])
+ raise DistributedOperationException(
+ f"Cannot apply desired operation due to shape mismatches. "
+ "All shapes across devices must be valid."
+ f"\n\nOperation: `{operation}`\nInput shapes:\n - {process_shape_str}"
+ )
+ return function(*args, **kwargs)
+
+ return wrapper
+
+
+def chained_operation(function):
+ """
+ Checks that `verify_operation` failed and if so reports a more helpful error chaining the existing
+ `DistributedOperationException`.
+ """
+
+ @wraps(function)
+ def wrapper(*args, **kwargs):
+ try:
+ return function(*args, **kwargs)
+ except DistributedOperationException as e:
+ operation = f"{function.__module__}.{function.__name__}"
+ raise DistributedOperationException(
+ f"Error found while calling `{operation}`. Please see the earlier error for more details."
+ ) from e
+
+ return wrapper
+
+
+@verify_operation
+def gather(tensor):
+ """
+ Recursively gather tensor in a nested list/tuple/dictionary of tensors from all devices.
+
+ Args:
+ tensor (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to gather.
+
+ Returns:
+ The same data structure as `tensor` with all tensors sent to the proper device.
+ """
+ if PartialState().distributed_type == DistributedType.XLA:
+ return _tpu_gather(tensor)
+ elif PartialState().distributed_type in TORCH_DISTRIBUTED_OPERATION_TYPES:
+ return _gpu_gather(tensor)
+ else:
+ return tensor
+
+
+def _gpu_gather_object(object: Any):
+ output_objects = [None for _ in range(PartialState().num_processes)]
+ torch.distributed.all_gather_object(output_objects, object)
+ # all_gather_object returns a list of lists, so we need to flatten it
+ return [x for y in output_objects for x in y]
+
+
+def gather_object(object: Any):
+ """
+ Recursively gather object in a nested list/tuple/dictionary of objects from all devices.
+
+ Args:
+ object (nested list/tuple/dictionary of picklable object):
+ The data to gather.
+
+ Returns:
+ The same data structure as `object` with all the objects sent to every device.
+ """
+ if PartialState().distributed_type == DistributedType.XLA:
+ raise NotImplementedError("gather objects in TPU is not supported")
+ elif PartialState().distributed_type in TORCH_DISTRIBUTED_OPERATION_TYPES:
+ return _gpu_gather_object(object)
+ else:
+ return object
+
+
+def _gpu_broadcast(data, src=0):
+ def _gpu_broadcast_one(tensor, src=0):
+ torch.distributed.broadcast(tensor, src=src)
+ return tensor
+
+ return recursively_apply(_gpu_broadcast_one, data, error_on_other_type=True, src=src)
+
+
+def _tpu_broadcast(tensor, src=0, name="broadcast tensor"):
+ if isinstance(tensor, (list, tuple)):
+ return honor_type(tensor, (_tpu_broadcast(t, name=f"{name}_{i}") for i, t in enumerate(tensor)))
+ elif isinstance(tensor, Mapping):
+ return type(tensor)({k: _tpu_broadcast(v, name=f"{name}_{k}") for k, v in tensor.items()})
+ return xm.mesh_reduce(name, tensor, lambda x: x[src])
+
+
+TENSOR_TYPE_TO_INT = {
+ torch.float: 1,
+ torch.double: 2,
+ torch.half: 3,
+ torch.bfloat16: 4,
+ torch.uint8: 5,
+ torch.int8: 6,
+ torch.int16: 7,
+ torch.int32: 8,
+ torch.int64: 9,
+ torch.bool: 10,
+}
+
+TENSOR_INT_TO_DTYPE = {v: k for k, v in TENSOR_TYPE_TO_INT.items()}
+
+
+def gather_tensor_shape(tensor):
+ """
+ Grabs the shape of `tensor` only available on one process and returns a tensor of its shape
+ """
+ # Allocate 80 bytes to store the shape
+ max_tensor_dimension = 2**20
+ state = PartialState()
+ base_tensor = torch.empty(max_tensor_dimension, dtype=torch.int, device=state.device)
+
+ # Since PyTorch can't just send a tensor to another GPU without
+ # knowing its size, we store the size of the tensor with data
+ # in an allocation
+ if tensor is not None:
+ shape = tensor.shape
+ tensor_dtype = TENSOR_TYPE_TO_INT[tensor.dtype]
+ base_tensor[: len(shape) + 1] = torch.tensor(list(shape) + [tensor_dtype], dtype=int)
+ # Perform a reduction to copy the size data onto all GPUs
+ base_tensor = reduce(base_tensor, reduction="sum")
+ base_tensor = base_tensor[base_tensor.nonzero()]
+ # The last non-zero data contains the coded dtype the source tensor is
+ dtype = int(base_tensor[-1:][0])
+ base_tensor = base_tensor[:-1]
+ return base_tensor, dtype
+
+
+def copy_tensor_to_devices(tensor=None) -> torch.Tensor:
+ """
+ Copies a tensor that only exists on a single device and broadcasts it to other devices. Differs from `broadcast` as
+ each worker doesn't need to know its shape when used (and tensor can be `None`)
+
+ Args:
+ tensor (`torch.tensor`):
+ The tensor that should be sent to all devices. Must only have it be defined on a single device, the rest
+ should be `None`.
+ """
+ state = PartialState()
+ shape, dtype = gather_tensor_shape(tensor)
+ if tensor is None:
+ tensor = torch.zeros(shape, dtype=TENSOR_INT_TO_DTYPE[dtype]).to(state.device)
+ return reduce(tensor, reduction="sum")
+
+
+@verify_operation
+def broadcast(tensor, from_process: int = 0):
+ """
+ Recursively broadcast tensor in a nested list/tuple/dictionary of tensors to all devices.
+
+ Args:
+ tensor (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to gather.
+ from_process (`int`, *optional*, defaults to 0):
+ The process from which to send the data
+
+ Returns:
+ The same data structure as `tensor` with all tensors broadcasted to the proper device.
+ """
+ if PartialState().distributed_type == DistributedType.XLA:
+ return _tpu_broadcast(tensor, src=from_process, name="accelerate.utils.broadcast")
+ elif PartialState().distributed_type in TORCH_DISTRIBUTED_OPERATION_TYPES:
+ return _gpu_broadcast(tensor, src=from_process)
+ else:
+ return tensor
+
+
+def broadcast_object_list(object_list, from_process: int = 0):
+ """
+ Broadcast a list of picklable objects from one process to the others.
+
+ Args:
+ object_list (list of picklable objects):
+ The list of objects to broadcast. This list will be modified inplace.
+ from_process (`int`, *optional*, defaults to 0):
+ The process from which to send the data.
+
+ Returns:
+ The same list containing the objects from process 0.
+ """
+ if PartialState().distributed_type == DistributedType.XLA:
+ for i, obj in enumerate(object_list):
+ object_list[i] = xm.mesh_reduce("accelerate.utils.broadcast_object_list", obj, lambda x: x[from_process])
+ elif PartialState().distributed_type in TORCH_DISTRIBUTED_OPERATION_TYPES:
+ torch.distributed.broadcast_object_list(object_list, src=from_process)
+ return object_list
+
+
+def slice_tensors(data, tensor_slice, process_index=None, num_processes=None):
+ """
+ Recursively takes a slice in a nested list/tuple/dictionary of tensors.
+
+ Args:
+ data (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to slice.
+ tensor_slice (`slice`):
+ The slice to take.
+
+ Returns:
+ The same data structure as `data` with all the tensors slices.
+ """
+
+ def _slice_tensor(tensor, tensor_slice):
+ return tensor[tensor_slice]
+
+ return recursively_apply(_slice_tensor, data, tensor_slice)
+
+
+def concatenate(data, dim=0):
+ """
+ Recursively concatenate the tensors in a nested list/tuple/dictionary of lists of tensors with the same shape.
+ If there is only a single batch of data, it is returned as-is.
+
+ Args:
+ data (nested list/tuple/dictionary of lists of tensors `torch.Tensor`):
+ The data to concatenate.
+ dim (`int`, *optional*, defaults to 0):
+ The dimension on which to concatenate.
+
+ Returns:
+ The same data structure as `data` with all the tensors concatenated.
+ """
+ if isinstance(data[0], (tuple, list)):
+ return honor_type(data[0], (concatenate([d[i] for d in data], dim=dim) for i in range(len(data[0]))))
+ elif isinstance(data[0], Mapping):
+ return type(data[0])({k: concatenate([d[k] for d in data], dim=dim) for k in data[0].keys()})
+ elif isinstance(data[0], torch.Tensor):
+ return torch.cat(data, dim=dim)
+ elif isinstance(data, (tuple, list)) and len(data) == 1:
+ return data[0]
+ else:
+ raise TypeError(f"Can only concatenate tensors but got {type(data[0])}")
+
+
+class CannotPadNestedTensorWarning(UserWarning):
+ pass
+
+
+@chained_operation
+def pad_across_processes(tensor, dim=0, pad_index=0, pad_first=False):
+ """
+ Recursively pad the tensors in a nested list/tuple/dictionary of tensors from all devices to the same size so they
+ can safely be gathered.
+
+ Args:
+ tensor (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to gather.
+ dim (`int`, *optional*, defaults to 0):
+ The dimension on which to pad.
+ pad_index (`int`, *optional*, defaults to 0):
+ The value with which to pad.
+ pad_first (`bool`, *optional*, defaults to `False`):
+ Whether to pad at the beginning or the end.
+ """
+
+ def _pad_across_processes(tensor, dim=0, pad_index=0, pad_first=False):
+ if getattr(tensor, "is_nested", False):
+ warnings.warn(
+ "Cannot pad nested tensors without more information. Leaving unprocessed.",
+ CannotPadNestedTensorWarning,
+ )
+ return tensor
+ if dim >= len(tensor.shape) or dim < -len(tensor.shape):
+ return tensor
+ # Convert negative dimensions to non-negative
+ if dim < 0:
+ dim += len(tensor.shape)
+
+ # Gather all sizes
+ size = torch.tensor(tensor.shape, device=tensor.device)[None]
+ sizes = gather(size).cpu()
+ # Then pad to the maximum size
+ max_size = max(s[dim] for s in sizes)
+ if max_size == tensor.shape[dim]:
+ return tensor
+
+ old_size = tensor.shape
+ new_size = list(old_size)
+ new_size[dim] = max_size
+ new_tensor = tensor.new_zeros(tuple(new_size)) + pad_index
+ if pad_first:
+ indices = tuple(
+ slice(max_size - old_size[dim], max_size) if i == dim else slice(None) for i in range(len(new_size))
+ )
+ else:
+ indices = tuple(slice(0, old_size[dim]) if i == dim else slice(None) for i in range(len(new_size)))
+ new_tensor[indices] = tensor
+ return new_tensor
+
+ return recursively_apply(
+ _pad_across_processes, tensor, error_on_other_type=True, dim=dim, pad_index=pad_index, pad_first=pad_first
+ )
+
+
+def pad_input_tensors(tensor, batch_size, num_processes, dim=0):
+ """
+ Takes a `tensor` of arbitrary size and pads it so that it can work given `num_processes` needed dimensions.
+
+ New tensors are just the last input repeated.
+
+ E.g.:
+ Tensor: ([3,4,4]) Num processes: 4 Expected result shape: ([4,4,4])
+
+ """
+
+ def _pad_input_tensors(tensor, batch_size, num_processes, dim=0):
+ remainder = batch_size // num_processes
+ last_inputs = batch_size - (remainder * num_processes)
+ if batch_size // num_processes == 0:
+ to_pad = num_processes - batch_size
+ else:
+ to_pad = num_processes - (batch_size // num_processes)
+ # In the rare case that `to_pad` is negative,
+ # we need to pad the last inputs - the found `to_pad`
+ if last_inputs > to_pad & to_pad < 1:
+ to_pad = last_inputs - to_pad
+ old_size = tensor.shape
+ new_size = list(old_size)
+ new_size[0] = batch_size + to_pad
+ new_tensor = tensor.new_zeros(tuple(new_size))
+ indices = tuple(slice(0, old_size[dim]) if i == dim else slice(None) for i in range(len(new_size)))
+ new_tensor[indices] = tensor
+ return new_tensor
+
+ return recursively_apply(
+ _pad_input_tensors,
+ tensor,
+ error_on_other_type=True,
+ batch_size=batch_size,
+ num_processes=num_processes,
+ dim=dim,
+ )
+
+
+@verify_operation
+def reduce(tensor, reduction="mean", scale=1.0):
+ """
+ Recursively reduce the tensors in a nested list/tuple/dictionary of lists of tensors across all processes by the
+ mean of a given operation.
+
+ Args:
+ tensor (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to reduce.
+ reduction (`str`, *optional*, defaults to `"mean"`):
+ A reduction method. Can be of "mean", "sum", or "none"
+ scale (`float`, *optional*):
+ A default scaling value to be applied after the reduce, only valid on XLA.
+
+ Returns:
+ The same data structure as `data` with all the tensors reduced.
+ """
+
+ def _reduce_across_processes(tensor, reduction="mean", scale=1.0):
+ state = PartialState()
+ cloned_tensor = tensor.clone()
+ if state.distributed_type == DistributedType.NO:
+ return cloned_tensor
+ if state.distributed_type == DistributedType.XLA:
+ # Some processes may have different HLO graphs than other
+ # processes, for example in the breakpoint API
+ # accelerator.set_trigger(). Use mark_step to make HLOs
+ # the same on all processes.
+ xm.mark_step()
+ xm.all_reduce(xm.REDUCE_SUM, [cloned_tensor], scale)
+ xm.mark_step()
+ elif state.distributed_type.value in TORCH_DISTRIBUTED_OPERATION_TYPES:
+ torch.distributed.all_reduce(cloned_tensor, ReduceOp.SUM)
+ if reduction == "mean":
+ cloned_tensor /= state.num_processes
+ return cloned_tensor
+
+ return recursively_apply(
+ _reduce_across_processes, tensor, error_on_other_type=True, reduction=reduction, scale=scale
+ )
+
+
+def convert_to_fp32(tensor):
+ """
+ Recursively converts the elements nested list/tuple/dictionary of tensors in FP16/BF16 precision to FP32.
+
+ Args:
+ tensor (nested list/tuple/dictionary of `torch.Tensor`):
+ The data to convert from FP16/BF16 to FP32.
+
+ Returns:
+ The same data structure as `tensor` with all tensors that were in FP16/BF16 precision converted to FP32.
+ """
+
+ def _convert_to_fp32(tensor):
+ return tensor.float()
+
+ def _is_fp16_bf16_tensor(tensor):
+ return (is_torch_tensor(tensor) or hasattr(tensor, "dtype")) and tensor.dtype in (
+ torch.float16,
+ torch.bfloat16,
+ )
+
+ return recursively_apply(_convert_to_fp32, tensor, test_type=_is_fp16_bf16_tensor)
+
+
+class ConvertOutputsToFp32:
+ """
+ Decorator to apply to a function outputting tensors (like a model forward pass) that ensures the outputs in FP16
+ precision will be convert back to FP32.
+
+ Args:
+ model_forward (`Callable`):
+ The function which outputs we want to treat.
+
+ Returns:
+ The same function as `model_forward` but with converted outputs.
+ """
+
+ def __init__(self, model_forward):
+ self.model_forward = model_forward
+ update_wrapper(self, model_forward)
+
+ def __call__(self, *args, **kwargs):
+ return convert_to_fp32(self.model_forward(*args, **kwargs))
+
+ def __getstate__(self):
+ raise pickle.PicklingError(
+ "Cannot pickle a prepared model with automatic mixed precision, please unwrap the model with `Accelerator.unwrap_model(model)` before pickling it."
+ )
+
+
+def convert_outputs_to_fp32(model_forward):
+ model_forward = ConvertOutputsToFp32(model_forward)
+
+ def forward(*args, **kwargs):
+ return model_forward(*args, **kwargs)
+
+ # To act like a decorator so that it can be popped when doing `extract_model_from_parallel`
+ forward.__wrapped__ = model_forward
+
+ return forward
+
+
+def find_device(data):
+ """
+ Finds the device on which a nested dict/list/tuple of tensors lies (assuming they are all on the same device).
+
+ Args:
+ (nested list/tuple/dictionary of `torch.Tensor`): The data we want to know the device of.
+ """
+ if isinstance(data, Mapping):
+ for obj in data.values():
+ device = find_device(obj)
+ if device is not None:
+ return device
+ elif isinstance(data, (tuple, list)):
+ for obj in data:
+ device = find_device(obj)
+ if device is not None:
+ return device
+ elif isinstance(data, torch.Tensor):
+ return data.device
+
+
+@contextmanager
+def GatheredParameters(params, modifier_rank=None, fwd_module=None, enabled=True):
+ """
+ Wrapper around `deepspeed.runtime.zero.GatheredParameters`, but if Zero-3 is not enabled, will be a no-op context
+ manager.
+ """
+ # We need to use the `AcceleratorState` here since it has access to the deepspeed plugin
+ if AcceleratorState().distributed_type != DistributedType.DEEPSPEED or (
+ AcceleratorState().deepspeed_plugin is not None
+ and not AcceleratorState().deepspeed_plugin.is_zero3_init_enabled()
+ ):
+ gather_param_context = nullcontext()
+ else:
+ import deepspeed
+
+ gather_param_context = deepspeed.zero.GatheredParameters(
+ params, modifier_rank=modifier_rank, fwd_module=fwd_module, enabled=enabled
+ )
+ with gather_param_context:
+ yield
diff --git a/tasks/tasksmith-3d762a2acfee/solution/solve.sh b/tasks/tasksmith-3d762a2acfee/solution/solve.sh
new file mode 100644
index 0000000000000000000000000000000000000000..13f1f59f1032266a5dc58538325272c961074609
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/solution/solve.sh
@@ -0,0 +1,3 @@
+#!/bin/sh
+set -eu
+cp /solution/reference/src/accelerate/utils/operations.py /workspace/src/accelerate/utils/operations.py
diff --git a/tasks/tasksmith-3d762a2acfee/task.toml b/tasks/tasksmith-3d762a2acfee/task.toml
new file mode 100644
index 0000000000000000000000000000000000000000..48dbe3987dcfce642427f890725cd1c20da4a338
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/task.toml
@@ -0,0 +1,102 @@
+schema_version = "1.3"
+artifacts = [
+ { source = "/workspace/src/accelerate/utils/operations.py" },
+]
+
+[task]
+name = "repo2rlenv/tasksmith-3d762a2acfee"
+
+[metadata.repo2env]
+recipe = "tasksmith"
+recipe_version = "1"
+source_url = "https://github.com/huggingface/accelerate/pull/3850"
+source_head = "bec8a3eda417b0f365a15f58556d4b66539935a2"
+source_base = "9a20895d4b7e7aa35ba9123a93c65948a53a6ec7"
+workspace_strategy = "head_minus_source_patch"
+source_diff_sha256 = "55a2741ed13782d8697e9c282ffc46f595fb37e98c9c8b5b2b6b4fe765d3b81e"
+acceptance_profile = "practical-generation-v1"
+reward_kinds = [
+ "test_execution",
+]
+quality_status = "exported"
+fail_to_pass_count = 4
+pass_to_pass_count = 7
+bundle_hash = "sha256:36f87bb9c29dd25abe01937baef7916870a09902343c29db2248bed55dc49a26"
+
+[metadata.repo2env.evaluation]
+schema_version = "1"
+status = "verified"
+stage = "complete"
+reason_codes = [
+ "quality_verified",
+]
+detail = "Reviewed controls, semantic probes and blind rollout passed the quality profile."
+checked_at = "2026-09-14T05:11:08.211137Z"
+provenance = "unknown"
+subject_bundle_hash = "sha256:36f87bb9c29dd25abe01937baef7916870a09902343c29db2248bed55dc49a26"
+profile = "practical-generation-v1"
+source_task_path = "/Users/adithya/projects/Repo2RLEnv-tasksmith/workspace/tasksmith-hf-scale/first-ten-v2/candidates/3d762a2acfee/quality/revisions/r1/tasksmith-3d762a2acfee"
+source_task_toml_sha256 = "b0bf8968e73beab8948211c253f61066eeb1494f05702ad41a4fe8a515ef7d7c"
+
+[[metadata.repo2env.evaluation.evidence]]
+kind = "quality_result"
+path = "/Users/adithya/projects/Repo2RLEnv-tasksmith/workspace/tasksmith-hf-scale/delivery/evidence/tasksmith-3d762a2acfee/quality-result.json"
+sha256 = "d200dc81a2854789fc14992fba879cc8483a83072bff2488e66009083369fd6a"
+subject_bundle_hash = "sha256:36f87bb9c29dd25abe01937baef7916870a09902343c29db2248bed55dc49a26"
+
+[[metadata.repo2env.evaluation.evidence]]
+kind = "baseline"
+path = "/Users/adithya/projects/Repo2RLEnv-tasksmith/workspace/tasksmith-hf-scale/first-ten-v2/candidates/3d762a2acfee/quality/trials/r1-baseline/ts-48f70f9184b6-q-3d762a2a-r1-baseline/tasksmith-3d762a2acfee__9sPsX4P/result.json"
+sha256 = "f9c1d542e9563525f7f632e0f4527fdbefe2b003e770de52c819e82ed3505c4b"
+subject_bundle_hash = "sha256:36f87bb9c29dd25abe01937baef7916870a09902343c29db2248bed55dc49a26"
+harbor_task_checksum = "575024500d56a7964a3569cf64e25bdf159b570ed721e1fa404daf8d4c55e973"
+
+[[metadata.repo2env.evaluation.evidence]]
+kind = "oracle"
+path = "/Users/adithya/projects/Repo2RLEnv-tasksmith/workspace/tasksmith-hf-scale/first-ten-v2/candidates/3d762a2acfee/quality/trials/r1-oracle/ts-48f70f9184b6-q-3d762a2a-r1-oracle/tasksmith-3d762a2acfee__YVzHbhr/result.json"
+sha256 = "39dbf3c1e4130fd73b57feecd7f59c1ef55bf5a59f7cd79a902835360892e813"
+subject_bundle_hash = "sha256:36f87bb9c29dd25abe01937baef7916870a09902343c29db2248bed55dc49a26"
+harbor_task_checksum = "575024500d56a7964a3569cf64e25bdf159b570ed721e1fa404daf8d4c55e973"
+
+[[metadata.repo2env.evaluation.evidence]]
+kind = "probe"
+path = "/Users/adithya/projects/Repo2RLEnv-tasksmith/workspace/tasksmith-hf-scale/first-ten-v2/candidates/3d762a2acfee/quality/trials/r1-probe0/ts-48f70f9184b6-q-3d762a2a-r1-probe0/tasksmith-3d762a2acfee__ZM7XbLA/result.json"
+sha256 = "876ce39c896969011890afbe844bf8b830d63d5f83c7820e6248258023088ea2"
+subject_bundle_hash = "sha256:8a504b9c9b28a876bf881fc622ab3061b340565ddf079c080348382d4498337e"
+harbor_task_checksum = "52a30f0232f79bf637f1c6f228eb2cf807ee3476b51b8c74e4369b1f1cd9d2ee"
+
+[[metadata.repo2env.evaluation.evidence]]
+kind = "probe"
+path = "/Users/adithya/projects/Repo2RLEnv-tasksmith/workspace/tasksmith-hf-scale/first-ten-v2/candidates/3d762a2acfee/quality/trials/r1-probe1/ts-48f70f9184b6-q-3d762a2a-r1-probe1/tasksmith-3d762a2acfee__6kiCj6g/result.json"
+sha256 = "c0a39af1b97172ab25d2345bd565e92e1a54f4225ec5e80234103cb353d70e5b"
+subject_bundle_hash = "sha256:052dac0c750270c56b231ee2575b43c7b9594bde2017ee4cfb6714cdec9dea7f"
+harbor_task_checksum = "16cb6c5d17a18eb20f21abff068551ab8c50f7ae1b8d316fdca20d194e982d06"
+
+[[metadata.repo2env.evaluation.evidence]]
+kind = "rollout"
+path = "/Users/adithya/projects/Repo2RLEnv-tasksmith/workspace/tasksmith-hf-scale/first-ten-v2/candidates/3d762a2acfee/quality/trials/r1-rollout/ts-48f70f9184b6-q-3d762a2a-r1-rollout/tasksmith-3d762a2acfee__tbZpEtZ/result.json"
+sha256 = "e1b3d896153aa350cc68177ab612d0a1491ead7ff3d8a1059753c68c1ee09812"
+subject_bundle_hash = "sha256:36f87bb9c29dd25abe01937baef7916870a09902343c29db2248bed55dc49a26"
+harbor_task_checksum = "575024500d56a7964a3569cf64e25bdf159b570ed721e1fa404daf8d4c55e973"
+
+[environment]
+cpus = 1
+memory_mb = 2048
+build_timeout_sec = 600
+network_mode = "no-network"
+
+[agent]
+timeout_sec = 600
+user = "learner"
+network_mode = "no-network"
+
+[verifier]
+timeout_sec = 120
+user = "root"
+network_mode = "no-network"
+environment_mode = "separate"
+
+[verifier.environment]
+network_mode = "no-network"
+cpus = 1
+memory_mb = 2048
diff --git a/tasks/tasksmith-3d762a2acfee/tests/Dockerfile b/tasks/tasksmith-3d762a2acfee/tests/Dockerfile
new file mode 100644
index 0000000000000000000000000000000000000000..89e5f59d75465d6c2b137aace4a4326f7ec28f33
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/Dockerfile
@@ -0,0 +1,9 @@
+FROM python:3.12-slim-bookworm
+WORKDIR /workspace
+RUN python -m pip install --no-cache-dir anyio==4.15.1 certifi==2026.7.22 filelock==3.32.3 fsspec==2026.7.0 huggingface_hub==1.31.0 httpx==0.28.1 httpcore==1.0.9 h11==0.16.0 idna==3.19 iniconfig==2.3.0 Jinja2==3.1.6 MarkupSafe==3.0.3 mpmath==1.3.0 networkx==3.6.1 numpy==2.5.3 packaging==26.3 parameterized==0.9.0 pluggy==1.6.0 psutil==7.2.2 pytest==8.4.2 PyYAML==6.0.3 safetensors==0.8.0 setuptools==78.1.0 sympy==1.14.0 torch==2.11.0+cpu tqdm==4.70.1 typing_extensions==4.16.0 wheel==0.48.0 --extra-index-url https://download.pytorch.org/whl/cpu
+COPY source /workspace
+RUN python -m pip install --no-cache-dir -e .
+ENV PYTHONDONTWRITEBYTECODE=1 PYTEST_DISABLE_PLUGIN_AUTOLOAD=1
+RUN useradd -m -u 1001 grader
+COPY grade.py test_driver.py test_results.py contract.json test.sh /tests/
+RUN chmod 755 /tests && chmod 644 /tests/*
diff --git a/tasks/tasksmith-3d762a2acfee/tests/contract.json b/tasks/tasksmith-3d762a2acfee/tests/contract.json
new file mode 100644
index 0000000000000000000000000000000000000000..94fb0f30a25affa8301229429e9af58e064eabcc
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/contract.json
@@ -0,0 +1 @@
+{"expected_passes": ["tests.tasksmith_behavior::test_dict_single_batch_mixed", "tests.tasksmith_behavior::test_single_non_tensor_passthrough", "tests.test_data_loader.DataLoaderTester::test_iterable_dataset_with_non_tensor_samples", "tests.test_utils.UtilsTester::test_concatenate", "tests.tasksmith_behavior::test_dict_multi_batch_non_tensor_raises", "tests.tasksmith_behavior::test_dict_multi_batch_tensors", "tests.tasksmith_behavior::test_list_of_tensors_preserved", "tests.tasksmith_behavior::test_multi_non_tensor_raises", "tests.tasksmith_behavior::test_tensor_concatenation_unchanged", "tests.tasksmith_behavior::test_tensor_custom_dim", "tests.tasksmith_behavior::test_tensor_single_element"], "submitted_files": ["src/accelerate/utils/operations.py"], "test_paths": ["tests/test_utils.py::UtilsTester::test_concatenate", "tests/test_data_loader.py::DataLoaderTester::test_iterable_dataset_with_non_tensor_samples", "tests/tasksmith_behavior.py"], "timeout_sec": 90}
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/grade.py b/tasks/tasksmith-3d762a2acfee/tests/grade.py
new file mode 100644
index 0000000000000000000000000000000000000000..a2eead39a559d14821a1955325a6682abe622a16
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/grade.py
@@ -0,0 +1,112 @@
+"""Standalone trusted entry point; copied into each separate verifier image.
+
+No Repo2RLEnv installation is needed to grade an exported task. Submitted Python
+runs as an unprivileged user; this parent owns the result parser and reward file.
+"""
+
+from __future__ import annotations
+
+import importlib.util
+import json
+import os
+import signal
+import stat
+import subprocess
+import sys
+import tempfile
+from pathlib import Path
+
+
+def main() -> None:
+ directory = Path("/tests")
+ parser_spec = importlib.util.spec_from_file_location(
+ "test_results", directory / "test_results.py"
+ )
+ parser = importlib.util.module_from_spec(parser_spec)
+ sys.modules[parser_spec.name] = parser
+ parser_spec.loader.exec_module(parser)
+ contract = json.loads((directory / "contract.json").read_text())
+ logs = Path("/logs/verifier")
+ logs.mkdir(parents=True, exist_ok=True)
+ logs.chmod(0o755)
+ reward = logs / "reward.txt"
+ reward.write_text("0\n")
+ reward.chmod(0o644)
+ for relative in contract["submitted_files"]:
+ path = Path("/workspace") / relative
+ # Artifact uploads are data. Refuse link traversal and special files
+ # before the child imports any learner-controlled code.
+ for component in (path, *path.parents):
+ if component.is_symlink():
+ raise ValueError("Submitted source contains a symlink")
+ if not stat.S_ISREG(path.stat().st_mode) or path.stat().st_size > 8 * 1024 * 1024:
+ raise ValueError("Submitted source is not a bounded regular file")
+ os.chown(path, 0, 0)
+ path.chmod(0o644)
+ with tempfile.TemporaryDirectory(prefix="r2e-grade-") as temporary:
+ working = Path(temporary)
+ os.chown(working, 1001, 1001)
+ working.chmod(0o700)
+ report = working / "results.xml"
+ command = [
+ "/usr/local/bin/python",
+ "-I",
+ "/tests/test_driver.py",
+ *contract["test_paths"],
+ "-q",
+ "--tb=short",
+ "-p",
+ "no:cacheprovider",
+ f"--junitxml={report}",
+ ]
+ with (logs / "stdout.txt").open("w") as stdout, (logs / "stderr.txt").open("w") as stderr:
+ process = subprocess.Popen(
+ command,
+ cwd="/workspace",
+ stdout=stdout,
+ stderr=stderr,
+ user=1001,
+ group=1001,
+ extra_groups=[],
+ start_new_session=True,
+ env={
+ "PATH": "/usr/local/bin:/usr/bin:/bin",
+ "HOME": temporary,
+ "PYTHONDONTWRITEBYTECODE": "1",
+ "PYTEST_DISABLE_PLUGIN_AUTOLOAD": "1",
+ },
+ )
+ try:
+ code = process.wait(timeout=contract["timeout_sec"])
+ finally:
+ # Terminate descendants too: they must not keep modifying the
+ # child-owned report while the trusted parent checks it.
+ try:
+ os.killpg(process.pid, signal.SIGKILL)
+ except ProcessLookupError:
+ pass
+ process.wait()
+ if report.is_symlink() or not report.is_file() or report.stat().st_size > 16 * 1024 * 1024:
+ (logs / "result.json").write_text(
+ json.dumps({"passed": False, "returncode": code, "reason": "invalid_report"})
+ )
+ return
+ text = report.read_text()
+ (logs / "results.xml").write_text(text)
+ try:
+ parsed = parser.parse_junit(text, returncode=code)
+ except ValueError as exc:
+ (logs / "result.json").write_text(
+ json.dumps({"passed": False, "returncode": code, "reason": str(exc)})
+ )
+ return
+ expected = set(contract["expected_passes"])
+ passed = code == 0 and bool(expected) and parsed.passed == expected
+ (logs / "result.json").write_text(
+ json.dumps({"passed": passed, "returncode": code, "statuses": parsed.statuses})
+ )
+ reward.write_text("1\n" if passed else "0\n")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.devcontainer/devcontainer.json b/tasks/tasksmith-3d762a2acfee/tests/source/.devcontainer/devcontainer.json
new file mode 100644
index 0000000000000000000000000000000000000000..7a0da2404899e9335e4ccd7559d7af36f825be37
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.devcontainer/devcontainer.json
@@ -0,0 +1,29 @@
+// File only needed for VSCode users to have proper Docker based interpreters
+{
+ "name": "accelerate_dev_environment",
+ "build": {
+ // ACTION NEEDED: comment/uncomment the relevant line depending on whether you are in a CPU/GPU environment
+ "dockerfile": "../docker/accelerate-cpu/Dockerfile"
+// "dockerfile": "../docker/accelerate-gpu/Dockerfile"
+ },
+ "runArgs": [
+ // ACTION NEEDED: uncomment the next line if your local machine has GPUs available
+// "--gpus", "all",
+ // Enable the docker container to access system resources
+ "--ipc", "host"
+ ],
+ "remoteEnv": {
+ "PYTHONPATH": "${containerEnv:PATH}:${containerWorkspaceFolder}"
+ },
+ "customizations": {
+ "vscode": {
+ "extensions": [
+ // Ensure we have IntelliSense in VSCode when running inside container
+ "ms-python.python"
+ ]
+ }
+ },
+ "workspaceFolder": "/workspaces/accelerate",
+ // Need git for VSCode to color code modifications. Only runs when building environment.
+ "onCreateCommand": "apt-get update && apt-get install -y git && pip install -e '.[dev]'"
+}
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/ISSUE_TEMPLATE/bug-report.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/ISSUE_TEMPLATE/bug-report.yml
new file mode 100644
index 0000000000000000000000000000000000000000..16111314f4f733d0551f3ce917a58e4ff74bda0e
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/ISSUE_TEMPLATE/bug-report.yml
@@ -0,0 +1,63 @@
+name: "\U0001F41B Bug Report"
+description: Submit a bug report to help us improve Accelerate
+body:
+ - type: markdown
+ attributes:
+ value: |
+ Thanks for taking the time to submit a bug report! 🐛
+ If this is not a bug related to the Accelerate library directly, but instead a general question about your code or the library specifically please use the [forums](https://discuss.huggingface.co/c/accelerate/18).
+
+ - type: textarea
+ id: system-info
+ attributes:
+ label: System Info
+ description: Please share your accelerate configuration with us. You can run the command `accelerate env` and copy-paste its outputs below
+ render: Shell
+ placeholder: accelerate version, OS, python version, numpy version, torch version, and accelerate's configuration
+ validations:
+ required: true
+
+ - type: checkboxes
+ id: information-scripts-examples
+ attributes:
+ label: Information
+ description: 'The problem arises when using:'
+ options:
+ - label: "The official example scripts"
+ - label: "My own modified scripts"
+
+ - type: checkboxes
+ id: information-tasks
+ attributes:
+ label: Tasks
+ description: "The tasks I am working on are:"
+ options:
+ - label: "One of the scripts in the examples/ folder of Accelerate or an officially supported `no_trainer` script in the `examples` folder of the `transformers` repo (such as `run_no_trainer_glue.py`)"
+ - label: "My own task or dataset (give details below)"
+
+ - type: textarea
+ id: reproduction
+ validations:
+ required: true
+ attributes:
+ label: Reproduction
+ description: |
+ Please provide a code sample that reproduces the problem you ran into. It can be a Colab link or just a code snippet.
+ If you have code snippets, error messages, stack traces please provide them here as well.
+ Important! Use code tags to correctly format your code. See https://help.github.com/en/github/writing-on-github/creating-and-highlighting-code-blocks#syntax-highlighting
+ Do not use screenshots, as they are hard to read and (more importantly) don't allow others to copy-and-paste your code.
+
+ placeholder: |
+ Steps to reproduce the behavior:
+
+ 1.
+ 2.
+ 3.
+
+ - type: textarea
+ id: expected-behavior
+ validations:
+ required: true
+ attributes:
+ label: Expected behavior
+ description: "A clear and concise description of what you would expect to happen."
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/PULL_REQUEST_TEMPLATE.md b/tasks/tasksmith-3d762a2acfee/tests/source/.github/PULL_REQUEST_TEMPLATE.md
new file mode 100644
index 0000000000000000000000000000000000000000..209169a7c1e2106256c5574f6b9b9d4c909f6e40
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/PULL_REQUEST_TEMPLATE.md
@@ -0,0 +1,47 @@
+# What does this PR do?
+
+
+
+
+
+Fixes # (issue)
+
+
+## Before submitting
+- [ ] This PR fixes a typo or improves the docs (you can dismiss the other checks if that's the case).
+- [ ] Did you read the [contributor guideline](https://github.com/huggingface/accelerate/blob/main/CONTRIBUTING.md#submitting-a-pull-request-pr),
+ Pull Request section?
+- [ ] Was this discussed/approved via a Github issue or the [forum](https://discuss.huggingface.co/)? Please add a link
+ to it if that's the case.
+- [ ] Did you make sure to update the documentation with your changes? Here are the
+ [documentation guidelines](https://github.com/huggingface/accelerate/tree/main/docs), and
+ [here are tips on formatting docstrings](https://github.com/huggingface/accelerate/tree/main/docs#writing-documentation---specification).
+- [ ] Did you write any new necessary tests?
+
+
+## Who can review?
+
+Anyone in the community is free to review the PR once the tests have passed. Feel free to tag
+members/contributors who may be interested in your PR.
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/build-docker-images-release.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/build-docker-images-release.yml
new file mode 100644
index 0000000000000000000000000000000000000000..29f1e7964951725eab86d0ad3a6fc06e46b4511a
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/build-docker-images-release.yml
@@ -0,0 +1,104 @@
+name: Build Docker images (releases)
+
+on:
+ workflow_dispatch:
+ release:
+ types: [published]
+
+concurrency:
+ group: docker-image-builds
+ cancel-in-progress: false
+
+jobs:
+ get-version:
+ runs-on: ubuntu-latest
+ outputs:
+ version: ${{ steps.step1.outputs.version }}
+ steps:
+ - uses: actions/checkout@v4
+ - id: step1
+ run: echo "version=$(python setup.py --version)" >> $GITHUB_OUTPUT
+
+ version-cpu:
+ name: "Latest Accelerate CPU [version]"
+ runs-on:
+ group: aws-general-8-plus
+ needs: get-version
+ steps:
+ - name: Set up Docker Buildx
+ uses: docker/setup-buildx-action@v2
+ - name: Login to DockerHub
+ uses: docker/login-action@v2
+ with:
+ username: ${{ secrets.DOCKERHUB_USERNAME }}
+ password: ${{ secrets.DOCKERHUB_PASSWORD }}
+
+ - name: Build and Push CPU
+ uses: docker/build-push-action@v4
+ with:
+ file: docker/accelerate-cpu/Dockerfile
+ push: true
+ tags: huggingface/accelerate:cpu-release-${{ needs.get-version.outputs.version }}
+
+ version-cuda:
+ name: "Latest Accelerate GPU [version]"
+ runs-on:
+ group: aws-g6-4xlarge-plus
+ needs: get-version
+ steps:
+ - name: Set up Docker Buildx
+ uses: docker/setup-buildx-action@v2
+ - name: Login to DockerHub
+ uses: docker/login-action@v2
+ with:
+ username: ${{ secrets.DOCKERHUB_USERNAME }}
+ password: ${{ secrets.DOCKERHUB_PASSWORD }}
+
+ - name: Build and Push GPU
+ uses: docker/build-push-action@v4
+ with:
+ file: docker/accelerate-gpu/Dockerfile
+ push: true
+ tags: huggingface/accelerate:gpu-release-${{needs.get-version.outputs.version}}
+
+ version-cuda-deepspeed:
+ name: "Latest Accelerate GPU DeepSpeed [version]"
+ runs-on:
+ group: aws-g6-4xlarge-plus
+ needs: get-version
+ steps:
+ - name: Set up Docker Buildx
+ uses: docker/setup-buildx-action@v2
+ - name: Login to DockerHub
+ uses: docker/login-action@v2
+ with:
+ username: ${{ secrets.DOCKERHUB_USERNAME }}
+ password: ${{ secrets.DOCKERHUB_PASSWORD }}
+
+ - name: Build and Push GPU
+ uses: docker/build-push-action@v4
+ with:
+ file: docker/accelerate-gpu-deepspeed/Dockerfile
+ push: true
+ tags: huggingface/accelerate:gpu-deepspeed-release-${{needs.get-version.outputs.version}}
+
+ version-cuda-fp8-transformerengine:
+ name: "Latest Accelerate GPU FP8 TransformerEngine [version]"
+ runs-on:
+ group: aws-g6-4xlarge-plus
+ needs: get-version
+ steps:
+ - name: Set up Docker Buildx
+ uses: docker/setup-buildx-action@v2
+ - name: Login to DockerHub
+ uses: docker/login-action@v2
+ with:
+ username: ${{ secrets.DOCKERHUB_USERNAME }}
+ password: ${{ secrets.DOCKERHUB_PASSWORD }}
+
+ - name: Build and Push GPU
+ uses: docker/build-push-action@v4
+ with:
+ file: docker/accelerate-gpu/Dockerfile
+ push: true
+ tags: huggingface/accelerate:gpu-fp8-transformerengine-release-${{needs.get-version.outputs.version}}
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/build_and_run_tests.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/build_and_run_tests.yml
new file mode 100644
index 0000000000000000000000000000000000000000..ba03bf983a6414b3d57ec4ece4c46062d814c360
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/build_and_run_tests.yml
@@ -0,0 +1,50 @@
+name: Trigger docker images and run tests
+
+on:
+ push:
+ branches:
+ - main
+ workflow_dispatch:
+
+env:
+ GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
+
+jobs:
+ check-for-source:
+ runs-on: ubuntu-latest
+ name: Check if setup was changed
+ outputs:
+ changed: ${{ steps.was_changed.outputs.changed }}
+ steps:
+ - uses: actions/checkout@v4
+ with:
+ fetch-depth: "2"
+
+ - name: Get changed files
+ id: changed-files
+ uses: tj-actions/changed-files@3f54ebb830831fc121d3263c1857cfbdc310cdb9 #v42
+
+ - name: Was setup changed
+ id: was_changed
+ run: |
+ for file in ${{ steps.changed-files.outputs.all_changed_files }}; do
+ if [ `basename "${file}"` == "setup.py" ]; then
+ echo "changed=1" >> $GITHUB_OUTPUT
+ fi
+ done
+
+ build-docker-containers:
+ needs: check-for-source
+ if: (github.event_name == 'push') && (needs.check-for-source.outputs.changed == '1')
+ uses: ./.github/workflows/build_docker_images.yml
+ secrets: inherit
+
+ run-merge-tests:
+ needs: build-docker-containers
+ if: always()
+ uses: ./.github/workflows/run_merge_tests.yml
+
+ run-integration-tests:
+ needs: build-docker-containers
+ if: always()
+ uses: ./.github/workflows/self_hosted_integration_tests.yml
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/build_docker_images.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/build_docker_images.yml
new file mode 100644
index 0000000000000000000000000000000000000000..8f45c5526a2940c2ab893ca6f870ddf9168be8c8
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/build_docker_images.yml
@@ -0,0 +1,116 @@
+name: Build Docker images (scheduled)
+
+on:
+ workflow_dispatch:
+ workflow_call:
+ schedule:
+ - cron: "0 1 * * *"
+
+concurrency:
+ group: docker-image-builds
+ cancel-in-progress: false
+
+jobs:
+ latest-cpu:
+ name: "Latest Accelerate CPU [dev]"
+ runs-on:
+ group: aws-general-8-plus
+ steps:
+ - name: Set up Docker Buildx
+ uses: docker/setup-buildx-action@v2
+ - name: Login to DockerHub
+ uses: docker/login-action@v2
+ with:
+ username: ${{ secrets.DOCKERHUB_USERNAME }}
+ password: ${{ secrets.DOCKERHUB_PASSWORD }}
+ - name: Get current date
+ id: date
+ run: |
+ echo "date=$(date '+%Y-%m-%d')" >> $GITHUB_ENV
+ - name: Build and Push CPU
+ uses: docker/build-push-action@v4
+ with:
+ file: docker/accelerate-cpu/Dockerfile
+ push: true
+ tags: |
+ huggingface/accelerate:cpu-nightly
+ huggingface/accelerate:cpu-nightly-${{ env.date }}
+
+ latest-cuda:
+ name: "Latest Accelerate GPU [dev]"
+ runs-on:
+ group: aws-g6-4xlarge-plus
+ steps:
+ - name: Set up Docker Buildx
+ uses: docker/setup-buildx-action@v2
+ - name: Login to DockerHub
+ uses: docker/login-action@v2
+ with:
+ username: ${{ secrets.DOCKERHUB_USERNAME }}
+ password: ${{ secrets.DOCKERHUB_PASSWORD }}
+ - name: Get current date
+ id: date
+ run: |
+ echo "date=$(date '+%Y-%m-%d')" >> $GITHUB_ENV
+ - name: Build and Push GPU
+ uses: docker/build-push-action@v4
+ with:
+ file: docker/accelerate-gpu/Dockerfile
+ push: true
+ tags: |
+ huggingface/accelerate:gpu-nightly
+ huggingface/accelerate:gpu-nightly-${{ env.date }}
+
+ latest-cuda-deepspeed:
+ name: "Latest Accelerate GPU DeepSpeed [dev]"
+ runs-on:
+ group: aws-g6-4xlarge-plus
+ steps:
+ - name: Set up Docker Buildx
+ uses: docker/setup-buildx-action@v2
+ - name: Login to DockerHub
+ uses: docker/login-action@v2
+ with:
+ username: ${{ secrets.DOCKERHUB_USERNAME }}
+ password: ${{ secrets.DOCKERHUB_PASSWORD }}
+ - name: Get current date
+ id: date
+ run: |
+ echo "date=$(date '+%Y-%m-%d')" >> $GITHUB_ENV
+ - name: Build and Push GPU
+ uses: docker/build-push-action@v4
+ with:
+ file: docker/accelerate-gpu-deepspeed/Dockerfile
+ push: true
+ tags: |
+ huggingface/accelerate:gpu-deepspeed-nightly
+ huggingface/accelerate:gpu-deepspeed-nightly-${{ env.date }}
+
+ latest-cuda-fp8-transformerengine:
+ name: "Latest Accelerate GPU FP8 TransformerEngine [dev]"
+ runs-on:
+ group: aws-g6-4xlarge-plus
+ steps:
+ - name: Set up Docker Buildx
+ uses: docker/setup-buildx-action@v2
+ - name: Login to DockerHub
+ uses: docker/login-action@v2
+ with:
+ username: ${{ secrets.DOCKERHUB_USERNAME }}
+ password: ${{ secrets.DOCKERHUB_PASSWORD }}
+ - name: Get current date
+ id: date
+ run: |
+ echo "date=$(date '+%Y-%m-%d')" >> $GITHUB_ENV
+ # Get the previous month
+ echo "base_year=$(date -d 'last month' '+%y')" >> $GITHUB_ENV
+ echo "base_month=$(date -d 'last month' '+%m')" >> $GITHUB_ENV
+ - name: Build and Push GPU
+ uses: docker/build-push-action@v4
+ with:
+ file: benchmarks/fp8/transformer_engine/Dockerfile
+ push: true
+ tags: huggingface/accelerate:gpu-fp8-transformerengine-nightly-${{ env.date }}
+ build-args: |
+ BASE_YEAR=${{ env.base_year }}
+ BASE_MONTH=${{ env.base_month }}
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/build_documentation.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/build_documentation.yml
new file mode 100644
index 0000000000000000000000000000000000000000..dc529d9dbfad72b24184ceb7f34a6b2da7dc9512
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/build_documentation.yml
@@ -0,0 +1,18 @@
+name: Build documentation
+
+on:
+ push:
+ branches:
+ - main
+ - doc-builder*
+ - v*-release
+
+jobs:
+ build:
+ uses: huggingface/doc-builder/.github/workflows/build_main_documentation.yml@main
+ with:
+ commit_sha: ${{ github.sha }}
+ package: accelerate
+ custom_container: huggingface/transformers-doc-builder
+ secrets:
+ hf_token: ${{ secrets.HF_DOC_BUILD_PUSH }}
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/build_pr_documentation.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/build_pr_documentation.yml
new file mode 100644
index 0000000000000000000000000000000000000000..7b8463e20b3e212d29eacbd31f5c5ae609029b2d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/build_pr_documentation.yml
@@ -0,0 +1,17 @@
+name: Build PR Documentation
+
+on:
+ pull_request:
+
+concurrency:
+ group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }}
+ cancel-in-progress: true
+
+jobs:
+ build:
+ uses: huggingface/doc-builder/.github/workflows/build_pr_documentation.yml@main
+ with:
+ commit_sha: ${{ github.event.pull_request.head.sha }}
+ pr_number: ${{ github.event.number }}
+ package: accelerate
+ custom_container: huggingface/transformers-doc-builder
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/fp8_runner.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/fp8_runner.yml
new file mode 100644
index 0000000000000000000000000000000000000000..91724a18581a573e90614daa58e31cf58b192d85
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/fp8_runner.yml
@@ -0,0 +1,37 @@
+name: Test FP8 Runner
+
+on:
+ workflow_dispatch:
+
+env:
+ GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
+jobs:
+ set-prev-day:
+ runs-on: ubuntu-latest
+ outputs:
+ prev-day: ${{ steps.set-prev-day.outputs.prev-day }}
+ steps:
+ - name: Set PREV_DAY
+ id: set-prev-day
+ run: |
+ PREV_DAY=$(date -d "yesterday" '+%Y-%m-%d')
+ echo "prev-day=$PREV_DAY" >> $GITHUB_OUTPUT
+ run-fp8-tests:
+ needs: set-prev-day
+ runs-on:
+ group: aws-g6e-12xlarge
+ container:
+ image: huggingface/accelerate:gpu-fp8-transformerengine-nightly-${{ needs.set-prev-day.outputs.prev-day }}
+ options: --gpus all --shm-size "16gb"
+ steps:
+ - uses: actions/checkout@v3
+ - name: Install the library
+ run: |
+ pip install -e .[test_prod,test_fp8]
+ - name: Show installed libraries
+ run: |
+ pip freeze
+ - name: Run TE FP8 tests
+ run: |
+ python -m pytest -s -v ./tests/test_fp8.py
+
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/gaudi3_scheduled.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/gaudi3_scheduled.yml
new file mode 100644
index 0000000000000000000000000000000000000000..f99a37ae3f8bf901924b35e44a33dc1df388cf92
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/gaudi3_scheduled.yml
@@ -0,0 +1,87 @@
+name: Gaudi3 tests (scheduled)
+
+on:
+ workflow_dispatch:
+ schedule: # every day at 6 AM UTC
+ - cron: "0 6 * * *"
+
+concurrency:
+ group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }}
+ cancel-in-progress: true
+
+jobs:
+ run-gaudi3-tests:
+ runs-on:
+ group: itac-bm-emr-gaudi3-dell-2gaudi
+
+ container:
+ image: docker://vault.habana.ai/gaudi-docker/1.21.1/ubuntu22.04/habanalabs/pytorch-installer-2.6.0:latest
+ options: --runtime=habana --shm-size=64G --cap-add=sys_nice --env HABANA_VISIBLE_DEVICES
+ env:
+ OMPI_MCA_btl_vader_single_copy_mechanism: none
+ PT_ENABLE_INT64_SUPPORT: 1
+ PT_HPU_LAZY_MODE: 0
+ RUN_SLOW: 1
+
+ steps:
+ - name: HL-SMI (1)
+ run: |
+ hl-smi
+ echo "HABANA_VISIBLE_DEVICES=${HABANA_VISIBLE_DEVICES}"
+ echo "HABANA_VISIBLE_MODULES=${HABANA_VISIBLE_MODULES}"
+
+ - name: Extract HPU visible modules
+ id: add-modules
+ run: |
+ export HABANA_VISIBLE_MODULES=$(hl-smi -Q module_id -f csv,noheader | tr '\n' ',' | sed 's/,$//')
+ echo "HABANA_VISIBLE_MODULES=${HABANA_VISIBLE_MODULES}" >> $GITHUB_ENV
+
+ - name: HL-SMI (2)
+ run: |
+ hl-smi
+ echo "HABANA_VISIBLE_DEVICES=${HABANA_VISIBLE_DEVICES}"
+ echo "HABANA_VISIBLE_MODULES=${HABANA_VISIBLE_MODULES}"
+
+ - name: Checkout to Accelerate
+ uses: actions/checkout@v4
+
+ - name: Install Accelerate with Transformers & DeepSpeed
+ run: |
+ pip install -e .[testing] \
+ git+https://github.com/HabanaAI/DeepSpeed.git@1.20.0 \
+ git+https://github.com/huggingface/transformers.git
+
+ - name: Run CLI tests
+ if: ${{ !cancelled() && (success() || failure()) }}
+ run: |
+ make test_cli
+
+ - name: Run Core tests
+ if: ${{ !cancelled() && (success() || failure()) }}
+ run: |
+ make test_core
+
+ - name: Run Big Modeling tests
+ if: ${{ !cancelled() && (success() || failure()) }}
+ run: |
+ make test_big_modeling
+
+ - name: Run DeepSpeed integration tests
+ if: ${{ !cancelled() && (success() || failure()) }}
+ run: |
+ make test_deepspeed
+
+ - name: Run FSDP integration tests
+ if: ${{ !cancelled() && (success() || failure()) }}
+ run: |
+ make test_fsdp
+
+ - name: Run TP integration tests
+ if: ${{ !cancelled() && (success() || failure()) }}
+ run: |
+ make test_tp
+
+ - name: Run Examples tests
+ if: ${{ !cancelled() && (success() || failure()) }}
+ run: |
+ make test_examples
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/integration_tests.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/integration_tests.yml
new file mode 100644
index 0000000000000000000000000000000000000000..cff91ac08c41505ffea97acc94d14a0110dd81ee
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/integration_tests.yml
@@ -0,0 +1,58 @@
+# CI for specifically ensuring integrations work fine (`transformers` mainly)
+# Useful tips:
+# - New integrations to test should have its own job, and follow a strategy method where we check both
+# the pypi and github versions.
+# - When checking the latest release of the integration, use
+# git checkout $(git describe --tags `git rev-list --tags --max-count=1`) to get the latest release.
+
+name: Integration Tests
+
+on:
+ pull_request:
+ paths:
+ - "src/**"
+ - "tests/**"
+ - ".github/**"
+ - "examples/**"
+ - "setup.py"
+ types: [opened, synchronize, reopened]
+
+env:
+ HF_HOME: ~/hf_cache
+
+jobs:
+ run-trainer-tests:
+ runs-on: ubuntu-latest
+ strategy:
+ fail-fast: false
+ steps:
+ - uses: actions/checkout@v4
+ - name: Set up python 3.10
+ uses: actions/setup-python@v5
+ with:
+ python-version: '3.10'
+ cache: 'pip'
+ cache-dependency-path: 'setup.py'
+
+ - name: Install Accelerate from source
+ run: |
+ pip install --upgrade pip
+ pip install -e .
+
+ - name: Clone and install transformers
+ run: |
+ cd ..
+ git clone https://github.com/huggingface/transformers
+ cd transformers
+ pip install .[torch,testing]
+
+ - name: Show installed libraries
+ run: |
+ pip freeze
+
+ - name: Run Trainer tests
+ env:
+ WANDB_DISABLED: true
+ run: |
+ cd ../transformers
+ pytest -sv tests/trainer
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/nightly.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/nightly.yml
new file mode 100644
index 0000000000000000000000000000000000000000..c1eb49e952bfdb930699c34d4c5911a5813e40b0
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/nightly.yml
@@ -0,0 +1,233 @@
+name: Self-hosted runner with slow tests (scheduled)
+
+on:
+ workflow_dispatch:
+ schedule:
+ - cron: "0 2 * * *"
+
+env:
+ RUN_SLOW: "yes"
+ IS_GITHUB_CI: "1"
+ SLACK_API_TOKEN: ${{ secrets.SLACK_API_TOKEN }}
+
+
+jobs:
+ run_core_tests_single_gpu:
+ runs-on:
+ group: aws-g6-4xlarge-plus
+ env:
+ CUDA_VISIBLE_DEVICES: "0"
+ TEST_TYPE: "single_gpu"
+ container:
+ image: huggingface/accelerate:gpu-nightly
+ options: --gpus all --shm-size "16gb"
+ defaults:
+ run:
+ shell: bash
+ steps:
+ - name: Update clone & pip install
+ run: |
+ source activate accelerate
+ git clone https://github.com/huggingface/accelerate;
+ cd accelerate;
+ git checkout ${{ github.sha }};
+ pip install -e . --no-deps
+ pip install pytest-reportlog tabulate
+
+ - name: Show installed libraries
+ run: |
+ source activate accelerate;
+ pip freeze
+
+ - name: Run test on GPUs
+ working-directory: accelerate
+ run: |
+ source activate accelerate
+ make test
+
+ - name: Run examples on GPUs
+ working-directory: accelerate
+ if: always()
+ run: |
+ source activate accelerate
+ pip uninstall comet_ml -y
+ make test_examples
+
+ - name: Generate Report
+ working-directory: accelerate
+ if: always()
+ run: |
+ pip install slack_sdk tabulate
+ python utils/log_reports.py >> $GITHUB_STEP_SUMMARY
+
+ run_deepspeed_tests_single_gpu:
+ runs-on:
+ group: aws-g6-4xlarge-plus
+ env:
+ CUDA_VISIBLE_DEVICES: "0"
+ TEST_TYPE: "single_gpu_deepspeed"
+ container:
+ image: huggingface/accelerate:gpu-deepspeed-nightly
+ options: --gpus all --shm-size "16gb"
+ defaults:
+ run:
+ shell: bash
+ steps:
+ - name: Update clone & pip install
+ run: |
+ source activate accelerate
+ git clone https://github.com/huggingface/accelerate;
+ cd accelerate;
+ git checkout ${{ github.sha }};
+ pip install -e . --no-deps
+ pip install pytest-reportlog tabulate
+
+ - name: Show installed libraries
+ run: |
+ source activate accelerate;
+ pip freeze
+
+ - name: Run test on GPUs
+ working-directory: accelerate
+ run: |
+ source activate accelerate
+ make test_deepspeed
+
+ - name: Run Integration tests on GPUs
+ working-directory: accelerate
+ if: always()
+ run: |
+ source activate accelerate
+ make test_integrations
+
+ - name: Run examples on GPUs
+ working-directory: accelerate
+ if: always()
+ run: |
+ source activate accelerate
+ pip uninstall comet_ml -y
+ make test_examples
+
+ - name: Generate Report
+ working-directory: accelerate
+ if: always()
+ run: |
+ pip install slack_sdk tabulate
+ python utils/log_reports.py >> $GITHUB_STEP_SUMMARY
+
+ run_core_tests_multi_gpu:
+ runs-on:
+ group: aws-g6-12xlarge-plus
+ env:
+ CUDA_VISIBLE_DEVICES: "0,1"
+ TEST_TYPE: "multi_gpu"
+ container:
+ image: huggingface/accelerate:gpu-nightly
+ options: --gpus all --shm-size "16gb"
+ defaults:
+ run:
+ shell: bash
+ steps:
+ - name: Update clone
+ run: |
+ source activate accelerate
+ git clone https://github.com/huggingface/accelerate;
+ cd accelerate;
+ git checkout ${{ github.sha }};
+ pip install -e . --no-deps
+ pip install pytest-reportlog tabulate
+
+ - name: Show installed libraries
+ run: |
+ source activate accelerate;
+ pip freeze
+
+ - name: Run core and big modeling tests on GPUs
+ working-directory: accelerate
+ run: |
+ source activate accelerate
+ make test_core
+ make test_big_modeling
+ make test_cli
+
+ - name: Run Integration tests on GPUs
+ working-directory: accelerate
+ if: always()
+ run: |
+ source activate accelerate
+ make test_integrations
+
+ - name: Run examples on GPUs
+ working-directory: accelerate
+ if: always()
+ run: |
+ source activate accelerate
+ pip uninstall comet_ml -y
+ make test_examples
+
+ - name: Generate Report
+ working-directory: accelerate
+ if: always()
+ run: |
+ pip install slack_sdk tabulate
+ python utils/log_reports.py >> $GITHUB_STEP_SUMMARY
+
+ run_deepspeed_tests_multi_gpu:
+ runs-on:
+ group: aws-g6-12xlarge-plus
+ env:
+ CUDA_VISIBLE_DEVICES: "0,1"
+ TEST_TYPE: "multi_gpu_deepspeed"
+ container:
+ image: huggingface/accelerate:gpu-deepspeed-nightly
+ options: --gpus all --shm-size "16gb"
+ defaults:
+ run:
+ shell: bash
+ steps:
+ - name: Update clone
+ run: |
+ source activate accelerate
+ git clone https://github.com/huggingface/accelerate;
+ cd accelerate;
+ git checkout ${{ github.sha }};
+ pip install -e . --no-deps
+ pip install pytest-reportlog tabulate
+
+ - name: Show installed libraries
+ run: |
+ source activate accelerate;
+ pip freeze
+
+ - name: Run DeepSpeed tests
+ working-directory: accelerate
+ run: |
+ source activate accelerate
+ make test_deepspeed
+
+ - name: Run Integration tests on GPUs
+ working-directory: accelerate
+ if: always()
+ run: |
+ source activate accelerate
+ make test_integrations
+
+ - name: Run examples on GPUs
+ working-directory: accelerate
+ if: always()
+ run: |
+ source activate accelerate
+ pip uninstall comet_ml -y
+ make test_examples
+
+ - name: Generate Report
+ working-directory: accelerate
+ if: always()
+ run: |
+ pip install slack_sdk tabulate
+ python utils/log_reports.py >> $GITHUB_STEP_SUMMARY
+
+
+ run-integration-tests:
+ if: always()
+ uses: ./.github/workflows/self_hosted_integration_tests.yml
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/pr_style_bot.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/pr_style_bot.yml
new file mode 100644
index 0000000000000000000000000000000000000000..cb337c44dcdd9c7da60363019dfa5e66ccbf9918
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/pr_style_bot.yml
@@ -0,0 +1,19 @@
+# To run this bot, comment "@bot /style" on a PR
+name: Style Bot
+
+on:
+ issue_comment:
+ types: [created]
+
+permissions:
+ contents: write
+ pull-requests: write
+
+jobs:
+ style:
+ uses: huggingface/huggingface_hub/.github/workflows/style-bot-action.yml@main
+ with:
+ python_quality_dependencies: "[quality]"
+ style_command_type: "default"
+ secrets:
+ bot_token: ${{ secrets.GITHUB_TOKEN }}
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/quality.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/quality.yml
new file mode 100644
index 0000000000000000000000000000000000000000..55e9ed3fbbd868cd9c4d6a247bfea0ecee53917b
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/quality.yml
@@ -0,0 +1,24 @@
+name: Quality Check
+
+on: [pull_request]
+
+jobs:
+ quality:
+ runs-on: ubuntu-latest
+ steps:
+ - uses: actions/checkout@v4
+ - name: Set up Python 3.10
+ uses: actions/setup-python@v5
+ with:
+ python-version: '3.10'
+ cache: 'pip'
+ cache-dependency-path: 'setup.py'
+ - name: Install Python dependencies
+ run: pip install -e .[quality]
+ - name: Run Quality check
+ run: make quality
+ - name: Check if failure
+ if: ${{ failure() }}
+ run: |
+ echo "Quality check failed. Please ensure the right dependency versions are installed with 'pip install -e .[quality]' and rerun 'make style; make quality;'" >> $GITHUB_STEP_SUMMARY
+
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/run_merge_tests.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/run_merge_tests.yml
new file mode 100644
index 0000000000000000000000000000000000000000..92a193a19c6017d9a005bafc3909341e5dde76aa
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/run_merge_tests.yml
@@ -0,0 +1,188 @@
+name: Self-hosted runner tests (push to "main")
+
+on:
+ workflow_call:
+ workflow_dispatch:
+
+env:
+ TESTING_MOCKED_DATALOADERS: "1"
+ IS_GITHUB_CI: "1"
+
+jobs:
+ run_core_tests_single_gpu:
+ runs-on:
+ group: aws-g6-4xlarge-plus
+ env:
+ CUDA_VISIBLE_DEVICES: "0"
+ container:
+ image: huggingface/accelerate:gpu-nightly
+ options: --gpus all --shm-size "16gb"
+ defaults:
+ run:
+ shell: bash
+ steps:
+ - name: Install accelerate
+ run: |
+ source activate accelerate;
+ git clone https://github.com/huggingface/accelerate;
+ cd accelerate;
+ git checkout ${{ github.sha }};
+ pip install -e .[testing,test_trackers] -U;
+ pip install pytest-reportlog tabulate ;
+
+ - name: Show installed libraries
+ run: |
+ source activate accelerate;
+ pip freeze
+
+ - name: Run CLI tests (use make cli)
+ working-directory: accelerate
+ run: |
+ source activate accelerate;
+ make test_cli
+
+ - name: Run test on GPUs
+ working-directory: accelerate
+ if: always()
+ run: |
+ source activate accelerate;
+ make test
+ - name: Run examples on GPUs
+ working-directory: accelerate
+ if: always()
+ run: |
+ source activate accelerate;
+ pip uninstall comet_ml -y;
+ make test_examples
+
+ - name: Generate Report
+ working-directory: accelerate
+ if: always()
+ run: |
+ pip install tabulate;
+ python utils/log_reports.py >> $GITHUB_STEP_SUMMARY
+
+ run_deepspeed_tests_single_gpu:
+ runs-on:
+ group: aws-g6-4xlarge-plus
+ env:
+ CUDA_VISIBLE_DEVICES: "0"
+ container:
+ image: huggingface/accelerate:gpu-deepspeed-nightly
+ options: --gpus all --shm-size "16gb"
+ defaults:
+ run:
+ shell: bash
+ steps:
+ - name: Install accelerate
+ run: |
+ source activate accelerate;
+ git clone https://github.com/huggingface/accelerate;
+ cd accelerate;
+ git checkout ${{ github.sha }};
+ pip install -e .[testing,test_trackers] -U;
+ pip install pytest-reportlog tabulate ;
+
+ - name: Show installed libraries
+ run: |
+ source activate accelerate;
+ pip freeze
+
+ - name: Run test on GPUs
+ working-directory: accelerate
+ if: always()
+ run: |
+ source activate accelerate;
+ make test_deepspeed
+
+ - name: Generate Report
+ working-directory: accelerate
+ if: always()
+ run: |
+ pip install tabulate;
+ python utils/log_reports.py >> $GITHUB_STEP_SUMMARY
+
+ run_core_tests_multi_gpu:
+ runs-on:
+ group: aws-g6-12xlarge-plus
+ env:
+ CUDA_VISIBLE_DEVICES: 0,1
+ container:
+ image: huggingface/accelerate:gpu-nightly
+ options: --gpus all --shm-size "16gb"
+ defaults:
+ run:
+ shell: bash
+ steps:
+ - name: Update clone
+ run: |
+ source activate accelerate;
+ git clone https://github.com/huggingface/accelerate;
+ cd accelerate;
+ git checkout ${{ github.sha }};
+ pip install -e .[testing,test_trackers] -U;
+ pip install pytest-reportlog tabulate
+
+ - name: Show installed libraries
+ run: |
+ source activate accelerate;
+ pip freeze
+
+ - name: Run test on GPUs
+ working-directory: accelerate
+ run: |
+ source activate accelerate;
+ make test
+
+ - name: Run examples on GPUs
+ working-directory: accelerate
+ if: always()
+ run: |
+ source activate accelerate;
+ pip uninstall comet_ml -y;
+ make test_examples
+
+ - name: Generate Report
+ working-directory: accelerate
+ if: always()
+ run: |
+ source activate accelerate;
+ python utils/log_reports.py >> $GITHUB_STEP_SUMMARY
+
+ run_deepspeed_tests_multi_gpu:
+ runs-on:
+ group: aws-g6-12xlarge-plus
+ container:
+ image: huggingface/accelerate:gpu-deepspeed-nightly
+ options: --gpus all --shm-size "16gb"
+ defaults:
+ run:
+ shell: bash
+ steps:
+ - name: Install accelerate
+ run: |
+ source activate accelerate;
+ git clone https://github.com/huggingface/accelerate;
+ cd accelerate;
+ git checkout ${{ github.sha }};
+ pip install -e .[testing,test_trackers] -U;
+ pip install pytest-reportlog tabulate ;
+
+ - name: Show installed libraries
+ run: |
+ source activate accelerate;
+ pip freeze
+
+ - name: Run test on GPUs
+ working-directory: accelerate
+ if: always()
+ run: |
+ source activate accelerate;
+ make test_deepspeed
+
+ - name: Generate Report
+ working-directory: accelerate
+ if: always()
+ run: |
+ pip install tabulate;
+ python utils/log_reports.py >> $GITHUB_STEP_SUMMARY
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/self_hosted_integration_tests.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/self_hosted_integration_tests.yml
new file mode 100644
index 0000000000000000000000000000000000000000..63c10e61f6ecc538c5a7ecd28f422dd51d5bcb2e
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/self_hosted_integration_tests.yml
@@ -0,0 +1,127 @@
+# CI for specifically ensuring integrations work fine (`transformers` mainly) on GPUs
+# Useful tips:
+# - `working-directory` should be set to the root of the repo, which is cloned on the actual CI runner.
+# It follows the directory structure of `actions-runner/_work/{repo_name}/{repo_name}/{cloned_repo} on
+# prem, but in Actions setting `working-directory` looks just in the `{repo_name}` level.
+# - New integrations to test should have its own job, and follow a strategy method where we check both
+# the pypi and github versions.
+# - Workflow call lets this be called from `build_and_run_tests.yml`
+# - When using a docker container, it's recommended to set `--shm-size`, we use 16gb.
+name: Integration Tests (push to "main")
+
+on:
+ workflow_call:
+ workflow_dispatch:
+
+env:
+ HF_HOME: ~/hf_cache
+
+defaults:
+ run:
+ shell: bash
+
+jobs:
+ run-trainer-tests:
+ container:
+ image: huggingface/accelerate:gpu-deepspeed-nightly
+ options: --gpus all --shm-size "16gb"
+ runs-on:
+ group: aws-g6-12xlarge-plus
+ strategy:
+ fail-fast: false
+ matrix:
+ cuda_visible_devices: [
+ "0",
+ "0,1"
+ ]
+ steps:
+ - name: Install transformers
+ run: |
+ source activate accelerate;
+ git clone https://github.com/huggingface/transformers --depth 1;
+ cd transformers;
+ pip install .[torch,deepspeed-testing];
+ cd ..;
+
+ - name: Install accelerate
+ run: |
+ source activate accelerate;
+ git clone https://github.com/huggingface/accelerate;
+ cd accelerate;
+ git checkout ${{ github.sha }} ;
+ pip install -e .[testing];
+ pip uninstall comet_ml wandb dvclive -y
+ cd ..;
+
+ - name: Show installed libraries
+ run: |
+ source activate accelerate;
+ pip freeze
+
+ - name: Run trainer tests
+ working-directory: transformers/
+ env:
+ CUDA_VISIBLE_DEVICES: ${{ matrix.cuda_visible_devices }}
+ WANDB_DISABLED: true
+ run: |
+ source activate accelerate;
+ pytest -sv tests/trainer
+
+ - name: Run deepspeed tests
+ working-directory: transformers/
+ env:
+ CUDA_VISIBLE_DEVICES: ${{ matrix.cuda_visible_devices }}
+ WANDB_DISABLED: true
+ if: always()
+ run: |
+ source activate accelerate;
+ pytest -sv tests/deepspeed
+
+ - name: Run transformers examples tests
+ working-directory: transformers/
+ env:
+ CUDA_VISIBLE_DEVICES: ${{ matrix.cuda_visible_devices }}
+ WANDB_DISABLED: true
+ run: |
+ source activate accelerate
+ pip install -r examples/pytorch/_tests_requirements.txt
+ pytest -sv examples/pytorch/test_accelerate_examples.py examples/pytorch/test_pytorch_examples.py
+
+ run-skorch-tests:
+ container:
+ image: huggingface/accelerate:gpu-nightly
+ options: --gpus all --shm-size "16gb"
+ runs-on:
+ group: aws-g6-12xlarge-plus
+ strategy:
+ fail-fast: false
+ steps:
+ - name: Install accelerate
+ run:
+ source activate accelerate;
+ git clone https://github.com/huggingface/accelerate;
+ cd accelerate;
+ git checkout ${{ github.sha }};
+ pip install -e .[testing];
+ cd ..
+
+ - name: Install skorch
+ run: |
+ source activate accelerate
+ git clone https://github.com/skorch-dev/skorch;
+ cd skorch;
+ git config --global --add safe.directory '*'
+ git checkout master && git pull
+ pip install .[test]
+ pip install flaky
+
+ - name: Show installed libraries
+ run: |
+ source activate accelerate;
+ pip freeze
+
+ - name: Run skorch tests
+ working-directory: skorch/
+ run: |
+ source activate accelerate;
+ pytest -sv -k TestAccelerate
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/stale.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/stale.yml
new file mode 100644
index 0000000000000000000000000000000000000000..fea407e2546259f8a66d833762f4e2da8a084812
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/stale.yml
@@ -0,0 +1,33 @@
+name: Stale Bot
+
+on:
+ schedule:
+ - cron: "0 15 * * *"
+ workflow_dispatch:
+
+jobs:
+ close_stale_issues:
+ name: Close Stale Issues
+ if: github.repository == 'huggingface/accelerate'
+ runs-on: ubuntu-latest
+ permissions:
+ issues: write
+ pull-requests: write
+ env:
+ GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
+ steps:
+ - uses: actions/checkout@v4
+
+ - name: Setup Python
+ uses: actions/setup-python@v5
+ with:
+ python-version: '3.10'
+ cache: 'pip'
+ cache-dependency-path: 'setup.py'
+
+ - name: Install requirements
+ run: |
+ pip install PyGithub
+ - name: Close stale issues
+ run: |
+ python utils/stale.py
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/test.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/test.yml
new file mode 100644
index 0000000000000000000000000000000000000000..975f53d296ef3dc862ed8a952bd47ab179a0c9c8
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/test.yml
@@ -0,0 +1,71 @@
+name: Run Tests
+
+on:
+ pull_request:
+ paths:
+ - "src/**"
+ - "tests/**"
+ - ".github/**"
+ - "examples/**"
+ - "setup.py"
+ types: [opened, synchronize, reopened]
+
+env:
+ HF_HOME: ~/hf_cache
+ TESTING_MOCKED_DATALOADERS: "1"
+ IS_GITHUB_CI: "1"
+
+jobs:
+ run-tests:
+ runs-on:
+ group: aws-general-8-plus
+ strategy:
+ fail-fast: false
+ matrix:
+ pytorch-version: [
+ latest,
+ minimum,
+ ]
+ test-kind: [
+ test_prod,
+ test_core,
+ test_cli,
+ test_big_modeling,
+ test_deepspeed,
+ test_fsdp,
+ test_example_differences,
+ test_checkpoint_step,
+ test_checkpoint_epoch,
+ test_rest
+ ]
+ steps:
+ - uses: actions/checkout@v4
+ - name: Set up python 3.10
+ uses: actions/setup-python@v5
+ with:
+ python-version: '3.10'
+ cache: 'pip'
+ cache-dependency-path: 'setup.py'
+
+ - name: Install the library
+ run: |
+ if [[ ${{ matrix.test-kind }} = test_prod ]]; then pip install -e .[test_prod]; fi
+ if [[ ${{ matrix.test-kind }} != test_prod ]]; then pip install -e .[testing,test_trackers]; fi
+ if [[ ${{ matrix.test-kind }} = test_rest ]]; then pip uninstall comet_ml -y; fi
+ if [[ ${{ matrix.pytorch-version }} = minimum ]]; then pip install torchvision==0.18.1 torch==2.3.1; fi
+ pip install pytest-reportlog tabulate setuptools importlib_metadata
+
+ - name: Show installed libraries
+ run: |
+ pip freeze
+
+ - name: Run Tests
+ env:
+ PYTORCH_VERSION: ${{ matrix.pytorch-version }}
+ run: |
+ make ${{ matrix.test-kind }}
+
+ - name: Generate Report
+ if: always()
+ run: |
+ python utils/log_reports.py >> $GITHUB_STEP_SUMMARY
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/test_imports.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/test_imports.yml
new file mode 100644
index 0000000000000000000000000000000000000000..0e86e870205263883752c32f2ef290612d1b6f78
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/test_imports.yml
@@ -0,0 +1,55 @@
+name: Run Import Tests
+
+on:
+ pull_request:
+ paths:
+ - "src/**"
+ - "tests/**"
+ - ".github/**"
+ - "examples/**"
+ - "setup.py"
+ types: [opened, synchronize, reopened]
+
+env:
+ HF_HOME: ~/hf_cache
+ TESTING_MOCKED_DATALOADERS: "1"
+ IS_GITHUB_CI: "1"
+
+jobs:
+ run-tests:
+ runs-on: ubuntu-latest
+ strategy:
+ fail-fast: false
+ matrix:
+ pytorch-version: [
+ latest,
+ minimum,
+ ]
+ steps:
+ - uses: actions/checkout@v4
+ - name: Set up python 3.10
+ uses: actions/setup-python@v5
+ with:
+ python-version: '3.10'
+ cache: 'pip'
+ cache-dependency-path: 'setup.py'
+
+ - name: Install the library
+ run: |
+ pip install -e .
+ pip install pytest-reportlog tabulate setuptools git+https://github.com/muellerzr/import-timer
+
+ - name: Show installed libraries
+ run: |
+ pip freeze
+
+ - name: Run Import Tests
+ env:
+ PYTORCH_VERSION: ${{ matrix.pytorch-version }}
+ run: |
+ pytest -sv tests/test_imports.py
+
+ - name: Generate Report
+ if: always()
+ run: |
+ python utils/log_reports.py >> $GITHUB_STEP_SUMMARY
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/trufflehog.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/trufflehog.yml
new file mode 100644
index 0000000000000000000000000000000000000000..9cbbf6803724dacc4759b69d7002bb34831e5937
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/trufflehog.yml
@@ -0,0 +1,15 @@
+on:
+ push:
+
+name: Secret Leaks
+
+jobs:
+ trufflehog:
+ runs-on: ubuntu-latest
+ steps:
+ - name: Checkout code
+ uses: actions/checkout@v4
+ with:
+ fetch-depth: 0
+ - name: Secret Scanning
+ uses: trufflesecurity/trufflehog@main
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/upload_pr_documentation.yml b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/upload_pr_documentation.yml
new file mode 100644
index 0000000000000000000000000000000000000000..fd6ed29f9f87a1e6e8364aead9740cf8a059e6a4
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.github/workflows/upload_pr_documentation.yml
@@ -0,0 +1,16 @@
+name: Upload PR Documentation
+
+on:
+ workflow_run:
+ workflows: ["Build PR Documentation"]
+ types:
+ - completed
+
+jobs:
+ build:
+ uses: huggingface/doc-builder/.github/workflows/upload_pr_documentation.yml@main
+ with:
+ package_name: accelerate
+ secrets:
+ hf_token: ${{ secrets.HF_DOC_BUILD_PUSH }}
+ comment_bot_token: ${{ secrets.COMMENT_BOT_TOKEN }}
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.gitignore b/tasks/tasksmith-3d762a2acfee/tests/source/.gitignore
new file mode 100644
index 0000000000000000000000000000000000000000..ff24394ddad2419878db4f3c27b44b2d8fb686ab
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.gitignore
@@ -0,0 +1,144 @@
+# Byte-compiled / optimized / DLL files
+__pycache__/
+*.py[cod]
+*$py.class
+
+# C extensions
+*.so
+
+# Distribution / packaging
+.Python
+build/
+develop-eggs/
+dist/
+downloads/
+eggs/
+.eggs/
+lib/
+lib64/
+parts/
+sdist/
+var/
+wheels/
+pip-wheel-metadata/
+share/python-wheels/
+*.egg-info/
+.installed.cfg
+*.egg
+MANIFEST
+
+# PyInstaller
+# Usually these files are written by a python script from a template
+# before PyInstaller builds the exe, so as to inject date/other infos into it.
+*.manifest
+*.spec
+
+# Installer logs
+pip-log.txt
+pip-delete-this-directory.txt
+
+# Unit test / coverage reports
+htmlcov/
+.tox/
+.nox/
+.coverage
+.coverage.*
+.cache
+nosetests.xml
+coverage.xml
+*.cover
+*.py,cover
+.hypothesis/
+.pytest_cache/
+
+# Translations
+*.mo
+*.pot
+
+# Django stuff:
+*.log
+local_settings.py
+db.sqlite3
+db.sqlite3-journal
+
+# Flask stuff:
+instance/
+.webassets-cache
+
+# Scrapy stuff:
+.scrapy
+
+# Sphinx documentation
+docs/_build/
+
+# PyBuilder
+target/
+
+# Jupyter Notebook
+.ipynb_checkpoints
+
+# IPython
+profile_default/
+ipython_config.py
+
+# pyenv
+.python-version
+
+# pipenv
+# According to pypa/pipenv#598, it is recommended to include Pipfile.lock in version control.
+# However, in case of collaboration, if having platform-specific dependencies or dependencies
+# having no cross-platform support, pipenv may install dependencies that don't work, or not
+# install all needed dependencies.
+#Pipfile.lock
+
+# PEP 582; used by e.g. github.com/David-OConnor/pyflow
+__pypackages__/
+
+# Celery stuff
+celerybeat-schedule
+celerybeat.pid
+
+# SageMath parsed files
+*.sage.py
+
+# Environments
+.env
+.venv
+env/
+venv/
+ENV/
+env.bak/
+venv.bak/
+
+# Spyder project settings
+.spyderproject
+.spyproject
+
+# Rope project settings
+.ropeproject
+
+# mkdocs documentation
+/site
+
+# mypy
+.mypy_cache/
+.dmypy.json
+dmypy.json
+
+# Pyre type checker
+.pyre/
+
+# VSCode
+.vscode
+
+# IntelliJ
+.idea
+
+# Mac .DS_Store
+.DS_Store
+
+# More test things
+wandb
+
+# ruff
+.ruff_cache
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/.pre-commit-config.yaml b/tasks/tasksmith-3d762a2acfee/tests/source/.pre-commit-config.yaml
new file mode 100644
index 0000000000000000000000000000000000000000..1563cffda8f500200924130ddf1e57497f6f2750
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/.pre-commit-config.yaml
@@ -0,0 +1,13 @@
+repos:
+ - repo: https://github.com/astral-sh/ruff-pre-commit
+ rev: v0.2.1
+ hooks:
+ - id: ruff
+ args:
+ - --fix
+ - id: ruff-format
+ - repo: https://github.com/pre-commit/pre-commit-hooks
+ rev: v4.5.0
+ hooks:
+ - id: check-merge-conflict
+ - id: check-yaml
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/CODE_OF_CONDUCT.md b/tasks/tasksmith-3d762a2acfee/tests/source/CODE_OF_CONDUCT.md
new file mode 100644
index 0000000000000000000000000000000000000000..c8ad966288a9faeeb71b2fad3ba12f6048e1a03f
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/CODE_OF_CONDUCT.md
@@ -0,0 +1,129 @@
+
+# Contributor Covenant Code of Conduct
+
+## Our Pledge
+
+We as members, contributors, and leaders pledge to make participation in our
+community a harassment-free experience for everyone, regardless of age, body
+size, visible or invisible disability, ethnicity, sex characteristics, gender
+identity and expression, level of experience, education, socio-economic status,
+nationality, personal appearance, race, religion, or sexual identity
+and orientation.
+
+We pledge to act and interact in ways that contribute to an open, welcoming,
+diverse, inclusive, and healthy community.
+
+## Our Standards
+
+Examples of behavior that contributes to a positive environment for our
+community include:
+
+* Demonstrating empathy and kindness toward other people
+* Being respectful of differing opinions, viewpoints, and experiences
+* Giving and gracefully accepting constructive feedback
+* Accepting responsibility and apologizing to those affected by our mistakes,
+ and learning from the experience
+* Focusing on what is best not just for us as individuals, but for the
+ overall community
+
+Examples of unacceptable behavior include:
+
+* The use of sexualized language or imagery, and sexual attention or
+ advances of any kind
+* Trolling, insulting or derogatory comments, and personal or political attacks
+* Public or private harassment
+* Publishing others' private information, such as a physical or email
+ address, without their explicit permission
+* Other conduct which could reasonably be considered inappropriate in a
+ professional setting
+
+## Enforcement Responsibilities
+
+Community leaders are responsible for clarifying and enforcing our standards of
+acceptable behavior and will take appropriate and fair corrective action in
+response to any behavior that they deem inappropriate, threatening, offensive,
+or harmful.
+
+Community leaders have the right and responsibility to remove, edit, or reject
+comments, commits, code, wiki edits, issues, and other contributions that are
+not aligned to this Code of Conduct, and will communicate reasons for moderation
+decisions when appropriate.
+
+## Scope
+
+This Code of Conduct applies within all community spaces, and also applies when
+an individual is officially representing the community in public spaces.
+Examples of representing our community include using an official e-mail address,
+posting via an official social media account, or acting as an appointed
+representative at an online or offline event.
+
+## Enforcement
+
+Instances of abusive, harassing, or otherwise unacceptable behavior may be
+reported to the community leaders responsible for enforcement at
+feedback@huggingface.co.
+All complaints will be reviewed and investigated promptly and fairly.
+
+All community leaders are obligated to respect the privacy and security of the
+reporter of any incident.
+
+## Enforcement Guidelines
+
+Community leaders will follow these Community Impact Guidelines in determining
+the consequences for any action they deem in violation of this Code of Conduct:
+
+### 1. Correction
+
+**Community Impact**: Use of inappropriate language or other behavior deemed
+unprofessional or unwelcome in the community.
+
+**Consequence**: A private, written warning from community leaders, providing
+clarity around the nature of the violation and an explanation of why the
+behavior was inappropriate. A public apology may be requested.
+
+### 2. Warning
+
+**Community Impact**: A violation through a single incident or series
+of actions.
+
+**Consequence**: A warning with consequences for continued behavior. No
+interaction with the people involved, including unsolicited interaction with
+those enforcing the Code of Conduct, for a specified period of time. This
+includes avoiding interactions in community spaces as well as external channels
+like social media. Violating these terms may lead to a temporary or
+permanent ban.
+
+### 3. Temporary Ban
+
+**Community Impact**: A serious violation of community standards, including
+sustained inappropriate behavior.
+
+**Consequence**: A temporary ban from any sort of interaction or public
+communication with the community for a specified period of time. No public or
+private interaction with the people involved, including unsolicited interaction
+with those enforcing the Code of Conduct, is allowed during this period.
+Violating these terms may lead to a permanent ban.
+
+### 4. Permanent Ban
+
+**Community Impact**: Demonstrating a pattern of violation of community
+standards, including sustained inappropriate behavior, harassment of an
+individual, or aggression toward or disparagement of classes of individuals.
+
+**Consequence**: A permanent ban from any sort of public interaction within
+the community.
+
+## Attribution
+
+This Code of Conduct is adapted from the [Contributor Covenant][homepage],
+version 2.0, available at
+https://www.contributor-covenant.org/version/2/0/code_of_conduct.html.
+
+Community Impact Guidelines were inspired by [Mozilla's code of conduct
+enforcement ladder](https://github.com/mozilla/diversity).
+
+[homepage]: https://www.contributor-covenant.org
+
+For answers to common questions about this code of conduct, see the FAQ at
+https://www.contributor-covenant.org/faq. Translations are available at
+https://www.contributor-covenant.org/translations.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/CONTRIBUTING.md b/tasks/tasksmith-3d762a2acfee/tests/source/CONTRIBUTING.md
new file mode 100644
index 0000000000000000000000000000000000000000..78ad064bd86b39a9f69c3bbd5be3910db1a93d8d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/CONTRIBUTING.md
@@ -0,0 +1,249 @@
+
+
+# How to contribute to 🤗 Accelerate?
+
+Everyone is welcome to contribute, and we value everybody's contribution. Code
+is thus not the only way to help the community. Answering questions, helping
+others, reaching out and improving the documentations are immensely valuable to
+the community.
+
+It also helps us if you spread the word: reference the library from blog posts
+on the awesome projects it made possible, shout out on Twitter every time it has
+helped you, or simply star the repo to say "thank you".
+
+Whichever way you choose to contribute, please be mindful to respect our
+[code of conduct](https://github.com/huggingface/accelerate/blob/main/CODE_OF_CONDUCT.md).
+
+## You can contribute in so many ways!
+
+Some of the ways you can contribute to Accelerate:
+* Fixing outstanding issues with the existing code;
+* Contributing to the examples or to the documentation;
+* Submitting issues related to bugs or desired new features.
+
+## Submitting a new issue or feature request
+
+Do your best to follow these guidelines when submitting an issue or a feature
+request. It will make it easier for us to come back to you quickly and with good
+feedback.
+
+### Did you find a bug?
+
+The 🤗 Accelerate library is robust and reliable thanks to the users who notify us of
+the problems they encounter. So thank you for reporting an issue.
+
+First, we would really appreciate it if you could **make sure the bug was not
+already reported** (use the search bar on Github under Issues).
+
+Did not find it? :( So we can act quickly on it, please follow these steps:
+
+* Include your **OS type and version**, the versions of **Python** and **PyTorch**.
+* A short, self-contained, code snippet that allows us to reproduce the bug in
+ less than 30s;
+* Provide the with your Accelerate configuration (located by default in `~/.cache/huggingface/accelerate/default_config.yaml`)
+
+### Do you want a new feature?
+
+A good feature request addresses the following points:
+
+1. Motivation first:
+* Is it related to a problem/frustration with the library? If so, please explain
+ why. Providing a code snippet that demonstrates the problem is best.
+* Is it related to something you would need for a project? We'd love to hear
+ about it!
+* Is it something you worked on and think could benefit the community?
+ Awesome! Tell us what problem it solved for you.
+2. Write a *full paragraph* describing the feature;
+3. Provide a **code snippet** that demonstrates its future use;
+4. In case this is related to a paper, please attach a link;
+5. Attach any additional information (drawings, screenshots, etc.) you think may help.
+
+If your issue is well written we're already 80% of the way there by the time you
+post it.
+
+## Submitting a pull request (PR)
+
+Before writing code, we strongly advise you to search through the existing PRs or
+issues to make sure that nobody is already working on the same thing. If you are
+unsure, it is always a good idea to open an issue to get some feedback.
+
+You will need basic `git` proficiency to be able to contribute to
+🤗 Accelerate. `git` is not the easiest tool to use but it has the greatest
+manual. Type `git --help` in a shell and enjoy. If you prefer books, [Pro
+Git](https://git-scm.com/book/en/v2) is a very good reference.
+
+Follow these steps to start contributing:
+
+1. Fork the [repository](https://github.com/huggingface/accelerate) by
+ clicking on the 'Fork' button on the repository's page. This creates a copy of the code
+ under your GitHub user account.
+
+2. Clone your fork to your local disk, and add the base repository as a remote. The following command
+ assumes you have your public SSH key uploaded to GitHub. See the following guide for more
+ [information](https://docs.github.com/en/repositories/creating-and-managing-repositories/cloning-a-repository).
+
+ ```bash
+ $ git clone git@github.com:/accelerate.git
+ $ cd accelerate
+ $ git remote add upstream https://github.com/huggingface/accelerate.git
+ ```
+
+3. Create a new branch to hold your development changes, and do this for every new PR you work on.
+
+ Start by synchronizing your `main` branch with the `upstream/main` branch (ore details in the [GitHub Docs](https://docs.github.com/en/github/collaborating-with-issues-and-pull-requests/syncing-a-fork)):
+
+ ```bash
+ $ git checkout main
+ $ git fetch upstream
+ $ git merge upstream/main
+ ```
+
+ Once your `main` branch is synchronized, create a new branch from it:
+
+ ```bash
+ $ git checkout -b a-descriptive-name-for-my-changes
+ ```
+
+ **Do not** work on the `main` branch.
+
+4. Set up a development environment by running the following command in a conda or a virtual environment you've created for working on this library:
+
+ ```bash
+ $ pip install -e ".[dev]"
+ ```
+
+ This will install all testing and linting/code quality dependencies for the library (see `quality`, `test_dev`,
+ `test_prod` targets in [`setup.py`](./setup.py)).
+
+ (If accelerate was already installed in the virtual environment, remove
+ it with `pip uninstall accelerate` before reinstalling it in editable
+ mode with the `-e` flag).
+
+ Alternatively, if you are using [Visual Studio Code](https://code.visualstudio.com/Download), the fastest way to get set up is by using
+ the provided Dev Container. Documentation on how to get started with dev containers is available [here](https://code.visualstudio.com/docs/remote/containers).
+
+5. Develop the features on your branch.
+
+ As you work on the features, you should make sure that the test suite
+ passes. You should run the tests impacted by your changes like this (see
+ below an explanation regarding the environment variable):
+
+ ```bash
+ $ pytest tests/.py
+ ```
+
+ > For the following commands leveraging the `make` utility, we recommend using the WSL system when running on
+ > Windows. More information [here](https://docs.microsoft.com/en-us/windows/wsl/about).
+
+ You can also run the full suite with the following command.
+
+ ```bash
+ $ make test
+ ```
+
+ `accelerate` relies on `ruff` to format its source code
+ consistently. After you make changes, apply automatic style corrections and code verifications
+ that can't be automated in one go with:
+
+ This target is also optimized to only work with files modified by the PR you're working on.
+
+ If you prefer to run the checks one after the other, the following command apply the
+ style corrections:
+
+ ```bash
+ $ make style
+ ```
+
+ `accelerate` also uses a few custom scripts to check for coding mistakes. Quality
+ control runs in CI, however you can also run the same checks with:
+
+ ```bash
+ $ make quality
+ ```
+
+ You can also set up [`pre-commit`](https://pre-commit.com/) to run these checks
+ automatically as Git commit hooks.
+
+ ```bash
+ $ pip install pre-commit
+ $ pre-commit install
+ ```
+
+ Once you're happy with your changes, add changed files using `git add` and
+ make a commit with `git commit` to record your changes locally:
+
+ ```bash
+ $ git add modified_file.py
+ $ git commit
+ ```
+
+ Please write [good commit messages](https://chris.beams.io/posts/git-commit/).
+
+ It is a good idea to sync your copy of the code with the original
+ repository regularly. This way you can quickly account for changes:
+
+ ```bash
+ $ git fetch upstream
+ $ git rebase upstream/main
+ ```
+
+ Push the changes to your account using:
+
+ ```bash
+ $ git push -u origin a-descriptive-name-for-my-changes
+ ```
+
+6. Once you are satisfied (**and the checklist below is happy too**), go to the
+ webpage of your fork on GitHub. Click on 'Pull request' to send your changes
+ to the project maintainers for review.
+
+7. It's ok if maintainers ask you for changes. It happens to core contributors
+ too! So everyone can see the changes in the Pull request, work in your local
+ branch and push the changes to your fork. They will automatically appear in
+ the pull request.
+
+
+### Checklist
+
+1. The title of your pull request should be a summary of its contribution;
+2. If your pull request addresses an issue, please mention the issue number in
+ the pull request description to make sure they are linked (and people
+ consulting the issue know you are working on it);
+3. To indicate a work in progress please prefix the title with `[WIP]`, or mark
+ the PR as a draft PR. These are useful to avoid duplicated work, and to differentiate
+ it from PRs ready to be merged;
+4. Make sure existing tests pass;
+5. Add high-coverage tests. No quality testing = no merge.
+
+See an example of a good PR here: https://github.com/huggingface/accelerate/pull/255
+
+### Tests
+
+An extensive test suite is included to test the library behavior and several examples. Library tests can be found in
+the [tests folder](https://github.com/huggingface/accelerate/tree/main/tests).
+
+We use `pytest` in order to run the tests. From the root of the
+repository, here's how to run tests with `pytest` for the library:
+
+```bash
+$ python -m pytest -sv ./tests
+```
+
+In fact, that's how `make test` is implemented (sans the `pip install` line)!
+
+You can specify a smaller set of tests in order to test only the feature
+you're working on.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/Dockerfile b/tasks/tasksmith-3d762a2acfee/tests/source/Dockerfile
new file mode 100644
index 0000000000000000000000000000000000000000..08a18fbdbd5ffc91dfbad5c5728451ca4b90418e
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/Dockerfile
@@ -0,0 +1,7 @@
+FROM python:3.12-slim-bookworm
+WORKDIR /workspace
+RUN python -m pip install --no-cache-dir anyio==4.15.1 certifi==2026.7.22 filelock==3.32.3 fsspec==2026.7.0 huggingface_hub==1.31.0 httpx==0.28.1 httpcore==1.0.9 h11==0.16.0 idna==3.19 iniconfig==2.3.0 Jinja2==3.1.6 MarkupSafe==3.0.3 mpmath==1.3.0 networkx==3.6.1 numpy==2.5.3 packaging==26.3 parameterized==0.9.0 pluggy==1.6.0 psutil==7.2.2 pytest==8.4.2 PyYAML==6.0.3 safetensors==0.8.0 setuptools==78.1.0 sympy==1.14.0 torch==2.11.0+cpu tqdm==4.70.1 typing_extensions==4.16.0 wheel==0.48.0 --extra-index-url https://download.pytorch.org/whl/cpu
+COPY . /workspace
+RUN python -m pip install --no-cache-dir -e .
+RUN rm -rf /workspace/.git /root/.cache/pip
+ENV PYTHONDONTWRITEBYTECODE=1 PYTEST_DISABLE_PLUGIN_AUTOLOAD=1
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/LICENSE b/tasks/tasksmith-3d762a2acfee/tests/source/LICENSE
new file mode 100644
index 0000000000000000000000000000000000000000..261eeb9e9f8b2b4b0d119366dda99c6fd7d35c64
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/LICENSE
@@ -0,0 +1,201 @@
+ Apache License
+ Version 2.0, January 2004
+ http://www.apache.org/licenses/
+
+ TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
+
+ 1. Definitions.
+
+ "License" shall mean the terms and conditions for use, reproduction,
+ and distribution as defined by Sections 1 through 9 of this document.
+
+ "Licensor" shall mean the copyright owner or entity authorized by
+ the copyright owner that is granting the License.
+
+ "Legal Entity" shall mean the union of the acting entity and all
+ other entities that control, are controlled by, or are under common
+ control with that entity. For the purposes of this definition,
+ "control" means (i) the power, direct or indirect, to cause the
+ direction or management of such entity, whether by contract or
+ otherwise, or (ii) ownership of fifty percent (50%) or more of the
+ outstanding shares, or (iii) beneficial ownership of such entity.
+
+ "You" (or "Your") shall mean an individual or Legal Entity
+ exercising permissions granted by this License.
+
+ "Source" form shall mean the preferred form for making modifications,
+ including but not limited to software source code, documentation
+ source, and configuration files.
+
+ "Object" form shall mean any form resulting from mechanical
+ transformation or translation of a Source form, including but
+ not limited to compiled object code, generated documentation,
+ and conversions to other media types.
+
+ "Work" shall mean the work of authorship, whether in Source or
+ Object form, made available under the License, as indicated by a
+ copyright notice that is included in or attached to the work
+ (an example is provided in the Appendix below).
+
+ "Derivative Works" shall mean any work, whether in Source or Object
+ form, that is based on (or derived from) the Work and for which the
+ editorial revisions, annotations, elaborations, or other modifications
+ represent, as a whole, an original work of authorship. For the purposes
+ of this License, Derivative Works shall not include works that remain
+ separable from, or merely link (or bind by name) to the interfaces of,
+ the Work and Derivative Works thereof.
+
+ "Contribution" shall mean any work of authorship, including
+ the original version of the Work and any modifications or additions
+ to that Work or Derivative Works thereof, that is intentionally
+ submitted to Licensor for inclusion in the Work by the copyright owner
+ or by an individual or Legal Entity authorized to submit on behalf of
+ the copyright owner. For the purposes of this definition, "submitted"
+ means any form of electronic, verbal, or written communication sent
+ to the Licensor or its representatives, including but not limited to
+ communication on electronic mailing lists, source code control systems,
+ and issue tracking systems that are managed by, or on behalf of, the
+ Licensor for the purpose of discussing and improving the Work, but
+ excluding communication that is conspicuously marked or otherwise
+ designated in writing by the copyright owner as "Not a Contribution."
+
+ "Contributor" shall mean Licensor and any individual or Legal Entity
+ on behalf of whom a Contribution has been received by Licensor and
+ subsequently incorporated within the Work.
+
+ 2. Grant of Copyright License. Subject to the terms and conditions of
+ this License, each Contributor hereby grants to You a perpetual,
+ worldwide, non-exclusive, no-charge, royalty-free, irrevocable
+ copyright license to reproduce, prepare Derivative Works of,
+ publicly display, publicly perform, sublicense, and distribute the
+ Work and such Derivative Works in Source or Object form.
+
+ 3. Grant of Patent License. Subject to the terms and conditions of
+ this License, each Contributor hereby grants to You a perpetual,
+ worldwide, non-exclusive, no-charge, royalty-free, irrevocable
+ (except as stated in this section) patent license to make, have made,
+ use, offer to sell, sell, import, and otherwise transfer the Work,
+ where such license applies only to those patent claims licensable
+ by such Contributor that are necessarily infringed by their
+ Contribution(s) alone or by combination of their Contribution(s)
+ with the Work to which such Contribution(s) was submitted. If You
+ institute patent litigation against any entity (including a
+ cross-claim or counterclaim in a lawsuit) alleging that the Work
+ or a Contribution incorporated within the Work constitutes direct
+ or contributory patent infringement, then any patent licenses
+ granted to You under this License for that Work shall terminate
+ as of the date such litigation is filed.
+
+ 4. Redistribution. You may reproduce and distribute copies of the
+ Work or Derivative Works thereof in any medium, with or without
+ modifications, and in Source or Object form, provided that You
+ meet the following conditions:
+
+ (a) You must give any other recipients of the Work or
+ Derivative Works a copy of this License; and
+
+ (b) You must cause any modified files to carry prominent notices
+ stating that You changed the files; and
+
+ (c) You must retain, in the Source form of any Derivative Works
+ that You distribute, all copyright, patent, trademark, and
+ attribution notices from the Source form of the Work,
+ excluding those notices that do not pertain to any part of
+ the Derivative Works; and
+
+ (d) If the Work includes a "NOTICE" text file as part of its
+ distribution, then any Derivative Works that You distribute must
+ include a readable copy of the attribution notices contained
+ within such NOTICE file, excluding those notices that do not
+ pertain to any part of the Derivative Works, in at least one
+ of the following places: within a NOTICE text file distributed
+ as part of the Derivative Works; within the Source form or
+ documentation, if provided along with the Derivative Works; or,
+ within a display generated by the Derivative Works, if and
+ wherever such third-party notices normally appear. The contents
+ of the NOTICE file are for informational purposes only and
+ do not modify the License. You may add Your own attribution
+ notices within Derivative Works that You distribute, alongside
+ or as an addendum to the NOTICE text from the Work, provided
+ that such additional attribution notices cannot be construed
+ as modifying the License.
+
+ You may add Your own copyright statement to Your modifications and
+ may provide additional or different license terms and conditions
+ for use, reproduction, or distribution of Your modifications, or
+ for any such Derivative Works as a whole, provided Your use,
+ reproduction, and distribution of the Work otherwise complies with
+ the conditions stated in this License.
+
+ 5. Submission of Contributions. Unless You explicitly state otherwise,
+ any Contribution intentionally submitted for inclusion in the Work
+ by You to the Licensor shall be under the terms and conditions of
+ this License, without any additional terms or conditions.
+ Notwithstanding the above, nothing herein shall supersede or modify
+ the terms of any separate license agreement you may have executed
+ with Licensor regarding such Contributions.
+
+ 6. Trademarks. This License does not grant permission to use the trade
+ names, trademarks, service marks, or product names of the Licensor,
+ except as required for reasonable and customary use in describing the
+ origin of the Work and reproducing the content of the NOTICE file.
+
+ 7. Disclaimer of Warranty. Unless required by applicable law or
+ agreed to in writing, Licensor provides the Work (and each
+ Contributor provides its Contributions) on an "AS IS" BASIS,
+ WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
+ implied, including, without limitation, any warranties or conditions
+ of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
+ PARTICULAR PURPOSE. You are solely responsible for determining the
+ appropriateness of using or redistributing the Work and assume any
+ risks associated with Your exercise of permissions under this License.
+
+ 8. Limitation of Liability. In no event and under no legal theory,
+ whether in tort (including negligence), contract, or otherwise,
+ unless required by applicable law (such as deliberate and grossly
+ negligent acts) or agreed to in writing, shall any Contributor be
+ liable to You for damages, including any direct, indirect, special,
+ incidental, or consequential damages of any character arising as a
+ result of this License or out of the use or inability to use the
+ Work (including but not limited to damages for loss of goodwill,
+ work stoppage, computer failure or malfunction, or any and all
+ other commercial damages or losses), even if such Contributor
+ has been advised of the possibility of such damages.
+
+ 9. Accepting Warranty or Additional Liability. While redistributing
+ the Work or Derivative Works thereof, You may choose to offer,
+ and charge a fee for, acceptance of support, warranty, indemnity,
+ or other liability obligations and/or rights consistent with this
+ License. However, in accepting such obligations, You may act only
+ on Your own behalf and on Your sole responsibility, not on behalf
+ of any other Contributor, and only if You agree to indemnify,
+ defend, and hold each Contributor harmless for any liability
+ incurred by, or claims asserted against, such Contributor by reason
+ of your accepting any such warranty or additional liability.
+
+ END OF TERMS AND CONDITIONS
+
+ APPENDIX: How to apply the Apache License to your work.
+
+ To apply the Apache License to your work, attach the following
+ boilerplate notice, with the fields enclosed by brackets "[]"
+ replaced with your own identifying information. (Don't include
+ the brackets!) The text should be enclosed in the appropriate
+ comment syntax for the file format. We also recommend that a
+ file or class name and description of purpose be included on the
+ same "printed page" as the copyright notice for easier
+ identification within third-party archives.
+
+ Copyright [yyyy] [name of copyright owner]
+
+ Licensed under the Apache License, Version 2.0 (the "License");
+ you may not use this file except in compliance with the License.
+ You may obtain a copy of the License at
+
+ http://www.apache.org/licenses/LICENSE-2.0
+
+ Unless required by applicable law or agreed to in writing, software
+ distributed under the License is distributed on an "AS IS" BASIS,
+ WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+ See the License for the specific language governing permissions and
+ limitations under the License.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/Makefile b/tasks/tasksmith-3d762a2acfee/tests/source/Makefile
new file mode 100644
index 0000000000000000000000000000000000000000..e5b35d999c09fe4af4e32257dc469c5f07d77abb
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/Makefile
@@ -0,0 +1,98 @@
+.PHONY: quality style test docs utils
+
+check_dirs := .
+
+# Check that source code meets quality standards
+
+extra_quality_checks:
+ python utils/check_copies.py
+ python utils/check_dummies.py
+ python utils/check_repo.py
+
+# this target runs checks on all files
+quality:
+ ruff check $(check_dirs)
+ ruff format --check $(check_dirs)
+
+# Format source code automatically and check is there are any problems left that need manual fixing
+style:
+ ruff check $(check_dirs) --fix
+ ruff format $(check_dirs)
+
+# Run tests for the library
+test_core:
+ python -m pytest -s -v ./tests/ \
+ --ignore=./tests/test_big_modeling.py \
+ --ignore=./tests/test_modeling_utils.py \
+ --ignore=./tests/test_examples.py \
+ --ignore=./tests/test_cli.py \
+ --ignore=./tests/deepspeed \
+ --ignore=./tests/fsdp \
+ --ignore=./tests/tp \
+ $(if $(IS_GITHUB_CI),--report-log "$(PYTORCH_VERSION)_core.log",)
+
+test_cli:
+ python -m pytest -s -v ./tests/test_cli.py $(if $(IS_GITHUB_CI),--report-log "$(PYTORCH_VERSION)_cli.log",)
+
+test_big_modeling:
+ python -m pytest -s -v ./tests/test_big_modeling.py ./tests/test_modeling_utils.py $(if $(IS_GITHUB_CI),--report-log "$(PYTORCH_VERSION)_big_modeling.log",)
+
+test_deepspeed:
+ python -m pytest -s -v ./tests/deepspeed $(if $(IS_GITHUB_CI),--report-log "$(PYTORCH_VERSION)_deepspeed.log",)
+
+test_fsdp:
+ python -m pytest -s -v ./tests/fsdp $(if $(IS_GITHUB_CI),--report-log "$(PYTORCH_VERSION)_fsdp.log",)
+
+test_tp:
+ python -m pytest -s -v ./tests/tp $(if $(IS_GITHUB_CI),--report-log "$(PYTORCH_VERSION)_tp.log",)
+
+# Since the new version of pytest will *change* how things are collected, we need `deepspeed` to
+# run after test_core and test_cli
+test:
+ $(MAKE) test_core
+ $(MAKE) test_cli
+ $(MAKE) test_big_modeling
+ $(MAKE) test_deepspeed
+ $(MAKE) test_fsdp
+ $(MAKE) test_tp
+
+test_examples:
+ python -m pytest -s -v ./tests/test_examples.py $(if $(IS_GITHUB_CI),--report-log "$(PYTORCH_VERSION)_examples.log",)
+
+# Broken down example tests for the CI runners
+test_integrations:
+ python -m pytest -s -v ./tests/fsdp ./tests/tp ./tests/deepspeed $(if $(IS_GITHUB_CI),--report-log "$(PYTORCH_VERSION)_integrations.log",)
+
+test_example_differences:
+ python -m pytest -s -v ./tests/test_examples.py::ExampleDifferenceTests $(if $(IS_GITHUB_CI),--report-log "$(PYTORCH_VERSION)_example_diff.log",)
+
+test_checkpoint_epoch:
+ python -m pytest -s -v ./tests/test_examples.py::FeatureExamplesTests -k "by_epoch" $(if $(IS_GITHUB_CI),--report-log "$(PYTORCH_VERSION)_checkpoint_epoch.log",)
+
+test_checkpoint_step:
+ python -m pytest -s -v ./tests/test_examples.py::FeatureExamplesTests -k "by_step" $(if $(IS_GITHUB_CI),--report-log "$(PYTORCH_VERSION)_checkpoint_step.log",)
+
+# Same as test but used to install only the base dependencies
+test_prod:
+ $(MAKE) test_core
+
+test_rest:
+ python -m pytest -s -v ./tests/test_examples.py::FeatureExamplesTests -k "not by_step and not by_epoch" $(if $(IS_GITHUB_CI),--report-log "$(PYTORCH_VERSION)_rest.log",)
+
+# For developers to prepare a release
+prepare_release:
+ rm -rf dist build
+ python setup.py bdist_wheel sdist
+
+# Make sure this is ran in a fresh venv of some form
+install_test_release:
+ pip uninstall accelerate -y
+ pip install -i https://testpypi.python.org/pypi --extra-index-url https://pypi.org/simple accelerate$(if $(version),==$(version),)
+
+# Run as `make target=testpypi upload_release`
+upload_release:
+ @if [ "$(target)" != "testpypi" ] && [ "$(target)" != "pypi" ]; then \
+ echo "Error: target must be either 'testpypi' or 'pypi'"; \
+ exit 1; \
+ fi
+ twine upload dist/* -r $(target)
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/README.md b/tasks/tasksmith-3d762a2acfee/tests/source/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..fc64f02e4fe4f570b155472720320cf165d1ede7
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/README.md
@@ -0,0 +1,277 @@
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
Run your *raw* PyTorch training script on any kind of device
+
+
+
+
+
+
+## Easy to integrate
+
+🤗 Accelerate was created for PyTorch users who like to write the training loop of PyTorch models but are reluctant to write and maintain the boilerplate code needed to use multi-GPUs/TPU/fp16.
+
+🤗 Accelerate abstracts exactly and only the boilerplate code related to multi-GPUs/TPU/fp16 and leaves the rest of your code unchanged.
+
+Here is an example:
+
+```diff
+ import torch
+ import torch.nn.functional as F
+ from datasets import load_dataset
++ from accelerate import Accelerator
+
++ accelerator = Accelerator()
+- device = 'cpu'
++ device = accelerator.device
+
+ model = torch.nn.Transformer().to(device)
+ optimizer = torch.optim.Adam(model.parameters())
+
+ dataset = load_dataset('my_dataset')
+ data = torch.utils.data.DataLoader(dataset, shuffle=True)
+
++ model, optimizer, data = accelerator.prepare(model, optimizer, data)
+
+ model.train()
+ for epoch in range(10):
+ for source, targets in data:
+ source = source.to(device)
+ targets = targets.to(device)
+
+ optimizer.zero_grad()
+
+ output = model(source)
+ loss = F.cross_entropy(output, targets)
+
+- loss.backward()
++ accelerator.backward(loss)
+
+ optimizer.step()
+```
+
+As you can see in this example, by adding 5-lines to any standard PyTorch training script you can now run on any kind of single or distributed node setting (single CPU, single GPU, multi-GPUs and TPUs) as well as with or without mixed precision (fp8, fp16, bf16).
+
+In particular, the same code can then be run without modification on your local machine for debugging or your training environment.
+
+🤗 Accelerate even handles the device placement for you (which requires a few more changes to your code, but is safer in general), so you can even simplify your training loop further:
+
+```diff
+ import torch
+ import torch.nn.functional as F
+ from datasets import load_dataset
++ from accelerate import Accelerator
+
+- device = 'cpu'
++ accelerator = Accelerator()
+
+- model = torch.nn.Transformer().to(device)
++ model = torch.nn.Transformer()
+ optimizer = torch.optim.Adam(model.parameters())
+
+ dataset = load_dataset('my_dataset')
+ data = torch.utils.data.DataLoader(dataset, shuffle=True)
+
++ model, optimizer, data = accelerator.prepare(model, optimizer, data)
+
+ model.train()
+ for epoch in range(10):
+ for source, targets in data:
+- source = source.to(device)
+- targets = targets.to(device)
+
+ optimizer.zero_grad()
+
+ output = model(source)
+ loss = F.cross_entropy(output, targets)
+
+- loss.backward()
++ accelerator.backward(loss)
+
+ optimizer.step()
+```
+
+Want to learn more? Check out the [documentation](https://huggingface.co/docs/accelerate) or have a look at our [examples](https://github.com/huggingface/accelerate/tree/main/examples).
+
+## Launching script
+
+🤗 Accelerate also provides an optional CLI tool that allows you to quickly configure and test your training environment before launching the scripts. No need to remember how to use `torch.distributed.run` or to write a specific launcher for TPU training!
+On your machine(s) just run:
+
+```bash
+accelerate config
+```
+
+and answer the questions asked. This will generate a config file that will be used automatically to properly set the default options when doing
+
+```bash
+accelerate launch my_script.py --args_to_my_script
+```
+
+For instance, here is how you would run the GLUE example on the MRPC task (from the root of the repo):
+
+```bash
+accelerate launch examples/nlp_example.py
+```
+
+This CLI tool is **optional**, and you can still use `python my_script.py` or `python -m torchrun my_script.py` at your convenience.
+
+You can also directly pass in the arguments you would to `torchrun` as arguments to `accelerate launch` if you wish to not run` accelerate config`.
+
+For example, here is how to launch on two GPUs:
+
+```bash
+accelerate launch --multi_gpu --num_processes 2 examples/nlp_example.py
+```
+
+To learn more, check the CLI documentation available [here](https://huggingface.co/docs/accelerate/package_reference/cli).
+
+Or view the configuration zoo [here](https://github.com/huggingface/accelerate/blob/main/examples/config_yaml_templates/)
+
+## Launching multi-CPU run using MPI
+
+🤗 Here is another way to launch multi-CPU run using MPI. You can learn how to install Open MPI on [this page](https://www.open-mpi.org/faq/?category=building#easy-build). You can use Intel MPI or MVAPICH as well.
+Once you have MPI setup on your cluster, just run:
+```bash
+accelerate config
+```
+Answer the questions that are asked, selecting to run using multi-CPU, and answer "yes" when asked if you want accelerate to launch mpirun.
+Then, use `accelerate launch` with your script like:
+```bash
+accelerate launch examples/nlp_example.py
+```
+Alternatively, you can use mpirun directly, without using the CLI like:
+```bash
+mpirun -np 2 python examples/nlp_example.py
+```
+
+## Launching training using DeepSpeed
+
+🤗 Accelerate supports training on single/multiple GPUs using DeepSpeed. To use it, you don't need to change anything in your training code; you can set everything using just `accelerate config`. However, if you desire to tweak your DeepSpeed related args from your Python script, we provide you the `DeepSpeedPlugin`.
+
+```python
+from accelerate import Accelerator, DeepSpeedPlugin
+
+# deepspeed needs to know your gradient accumulation steps beforehand, so don't forget to pass it
+# Remember you still need to do gradient accumulation by yourself, just like you would have done without deepspeed
+deepspeed_plugin = DeepSpeedPlugin(zero_stage=2, gradient_accumulation_steps=2)
+accelerator = Accelerator(mixed_precision='fp16', deepspeed_plugin=deepspeed_plugin)
+
+# How to save your 🤗 Transformer?
+accelerator.wait_for_everyone()
+unwrapped_model = accelerator.unwrap_model(model)
+unwrapped_model.save_pretrained(save_dir, save_function=accelerator.save, state_dict=accelerator.get_state_dict(model))
+```
+
+Note: DeepSpeed support is experimental for now. In case you get into some problem, please open an issue.
+
+## Launching your training from a notebook
+
+🤗 Accelerate also provides a `notebook_launcher` function you can use in a notebook to launch a distributed training. This is especially useful for Colab or Kaggle notebooks with a TPU backend. Just define your training loop in a `training_function` then in your last cell, add:
+
+```python
+from accelerate import notebook_launcher
+
+notebook_launcher(training_function)
+```
+
+An example can be found in [this notebook](https://github.com/huggingface/notebooks/blob/main/examples/accelerate_examples/simple_nlp_example.ipynb). [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/accelerate_examples/simple_nlp_example.ipynb)
+
+## Why should I use 🤗 Accelerate?
+
+You should use 🤗 Accelerate when you want to easily run your training scripts in a distributed environment without having to renounce full control over your training loop. This is not a high-level framework above PyTorch, just a thin wrapper so you don't have to learn a new library. In fact, the whole API of 🤗 Accelerate is in one class, the `Accelerator` object.
+
+## Why shouldn't I use 🤗 Accelerate?
+
+You shouldn't use 🤗 Accelerate if you don't want to write a training loop yourself. There are plenty of high-level libraries above PyTorch that will offer you that, 🤗 Accelerate is not one of them.
+
+## Frameworks using 🤗 Accelerate
+
+If you like the simplicity of 🤗 Accelerate but would prefer a higher-level abstraction around its capabilities, some frameworks and libraries that are built on top of 🤗 Accelerate are listed below:
+
+* [Amphion](https://github.com/open-mmlab/Amphion) is a toolkit for Audio, Music, and Speech Generation. Its purpose is to support reproducible research and help junior researchers and engineers get started in the field of audio, music, and speech generation research and development.
+* [Animus](https://github.com/Scitator/animus) is a minimalistic framework to run machine learning experiments. Animus highlights common "breakpoints" in ML experiments and provides a unified interface for them within [IExperiment](https://github.com/Scitator/animus/blob/main/animus/core.py#L76).
+* [Catalyst](https://github.com/catalyst-team/catalyst#getting-started) is a PyTorch framework for Deep Learning Research and Development. It focuses on reproducibility, rapid experimentation, and codebase reuse so you can create something new rather than write yet another train loop. Catalyst provides a [Runner](https://catalyst-team.github.io/catalyst/api/core.html#runner) to connect all parts of the experiment: hardware backend, data transformations, model training, and inference logic.
+* [fastai](https://github.com/fastai/fastai#installing) is a PyTorch framework for Deep Learning that simplifies training fast and accurate neural nets using modern best practices. fastai provides a [Learner](https://docs.fast.ai/learner.html#Learner) to handle the training, fine-tuning, and inference of deep learning algorithms.
+* [Finetuner](https://github.com/jina-ai/finetuner) is a service that enables models to create higher-quality embeddings for semantic search, visual similarity search, cross-modal text<->image search, recommendation systems, clustering, duplication detection, anomaly detection, or other uses.
+* [InvokeAI](https://github.com/invoke-ai/InvokeAI) is a creative engine for Stable Diffusion models, offering industry-leading WebUI, terminal usage support, and serves as the foundation for many commercial products.
+* [Kornia](https://kornia.readthedocs.io/en/latest/get-started/introduction.html) is a differentiable library that allows classical computer vision to be integrated into deep learning models. Kornia provides a [Trainer](https://kornia.readthedocs.io/en/latest/x.html#kornia.x.Trainer) with the specific purpose to train and fine-tune the supported deep learning algorithms within the library.
+* [Open Assistant](https://projects.laion.ai/Open-Assistant/) is a chat-based assistant that understands tasks, can interact with their party systems, and retrieve information dynamically to do so.
+* [pytorch-accelerated](https://github.com/Chris-hughes10/pytorch-accelerated) is a lightweight training library, with a streamlined feature set centered around a general-purpose [Trainer](https://pytorch-accelerated.readthedocs.io/en/latest/trainer.html), that places a huge emphasis on simplicity and transparency; enabling users to understand exactly what is going on under the hood, but without having to write and maintain the boilerplate themselves!
+* [Stable Diffusion web UI](https://github.com/AUTOMATIC1111/stable-diffusion-webui) is an open-source browser-based easy-to-use interface based on the Gradio library for Stable Diffusion.
+* [torchkeras](https://github.com/lyhue1991/torchkeras) is a simple tool for training pytorch model just in a keras style, a dynamic and beautiful plot is provided in notebook to monitor your loss or metric.
+* [transformers](https://github.com/huggingface/transformers) as a tool for helping train state-of-the-art machine learning models in PyTorch, Tensorflow, and JAX. (Accelerate is the backend for the PyTorch side).
+
+
+## Installation
+
+This repository is tested on Python 3.8+ and PyTorch 1.10.0+
+
+You should install 🤗 Accelerate in a [virtual environment](https://docs.python.org/3/library/venv.html). If you're unfamiliar with Python virtual environments, check out the [user guide](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/).
+
+First, create a virtual environment with the version of Python you're going to use and activate it.
+
+Then, you will need to install PyTorch: refer to the [official installation page](https://pytorch.org/get-started/locally/#start-locally) regarding the specific install command for your platform. Then 🤗 Accelerate can be installed using pip as follows:
+
+```bash
+pip install accelerate
+```
+
+## Supported integrations
+
+- CPU only
+- multi-CPU on one node (machine)
+- multi-CPU on several nodes (machines)
+- single GPU
+- multi-GPU on one node (machine)
+- multi-GPU on several nodes (machines)
+- TPU
+- FP16/BFloat16 mixed precision
+- FP8 mixed precision with [Transformer Engine](https://github.com/NVIDIA/TransformerEngine) or [MS-AMP](https://github.com/Azure/MS-AMP/)
+- DeepSpeed support (Experimental)
+- PyTorch Fully Sharded Data Parallel (FSDP) support (Experimental)
+- Megatron-LM support (Experimental)
+
+## Citing 🤗 Accelerate
+
+If you use 🤗 Accelerate in your publication, please cite it by using the following BibTeX entry.
+
+```bibtex
+@Misc{accelerate,
+ title = {Accelerate: Training and inference at scale made simple, efficient and adaptable.},
+ author = {Sylvain Gugger and Lysandre Debut and Thomas Wolf and Philipp Schmid and Zachary Mueller and Sourab Mangrulkar and Marc Sun and Benjamin Bossan},
+ howpublished = {\url{https://github.com/huggingface/accelerate}},
+ year = {2022}
+}
+```
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/README.md b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..0a2381ac4182437151c1840847970bb6ade6bcbe
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/README.md
@@ -0,0 +1,5 @@
+# Benchmarks
+
+The folders below contain suites to test various functionalities in Accelerate.
+
+See their relevant README.md's for more information.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/big_model_inference/README.md b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/big_model_inference/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..8736bec246721a73e5089cd0a3492e1ff687db8d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/big_model_inference/README.md
@@ -0,0 +1,46 @@
+# Big model inference benchmarks
+
+Running inference with Accelerate on big models.
+
+## Setup
+
+These benchmarks use the `transformers` library:
+
+```bash
+pip install transformers
+```
+
+To reproduce or test a new setup, run
+
+```py
+python big_model_inference.py model_name
+```
+
+This script supports `gpt-j-6b`, `gpt-neox`, `opt` (30B version) and `T0pp` out of the box, but you can specify any valid checkpoint for `model_name`.
+
+To force a different `torch_dtype` than the one in the config: `--torch_dtype xxx`.
+
+If you get an error linked to disk offload, you need to add the option `--disk-offload`
+
+## Results
+
+On a setup with two Titan RTXs (24GB of RAM) and 32GB of RAM, we get the following benchmarks (T0pp does not run in float16, which is why it's not included).
+
+| Model | Model load time | Generation time | dtype | GPU 0 use | GPU 1 use | CPU use | Disk offload |
+|:-----:|:---------------:|:---------------:|:-----:|:---------:|:---------:|:-------:|:------------:|
+| GPT-J-6B | 8.7s | 0.05s per token | float16 | 11.7GB | 0GB | 0GB | no |
+| GPT-J-6B | 12.4s | 0.06s per token | float32 | 21.9GB | 1.5GB | 0GB | no |
+| GPT-Neo-X-20B | 30.9s | 0.08s per token | float16 | 21.5GB | 18GB | 0GB | no |
+| GPT-Neo-X-20B | 78.2s | 10.72s per token | float32 | 20.3GB | 22.7 GB | 24.4GB | yes |
+| T0pp (11B) | 29.4s | 0.05s per token | float32 | 21.1GB | 21.3GB | 0GB | no |
+| OPT-30B | 34.5s | 2.37s per token | float16 | 20.7GB | 22.3GB | 14.1GB | no |
+| OPT-30B | 112.3s | 33.9s per token | float32 | 20.2GB | 21.2GB | 23.5GB | yes |
+
+Note on the results:
+- using two GPUs instead of one does not slow down generation
+- using CPU offload slows down a bit (see OPT-30b)
+- using disk offload slows down a lot (need to implement prefetching)
+
+You will also note that Accelerate does not use anymore GPU and CPU RAM than necessary:
+- peak GPU memory is exactly the size of the model put on a given GPU
+- peak CPU memory is either the size of the biggest checkpoint shard or the part of the model offloaded on CPU, whichever is bigger.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/big_model_inference/big_model_inference.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/big_model_inference/big_model_inference.py
new file mode 100644
index 0000000000000000000000000000000000000000..d7874e625805c5f9581508dbe69f4456adfdae4a
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/big_model_inference/big_model_inference.py
@@ -0,0 +1,143 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import argparse
+import time
+
+import torch
+import transformers
+from measures_util import end_measure, log_measures, start_measure
+from transformers import AutoConfig, AutoModelForCausalLM, AutoModelForSeq2SeqLM, AutoTokenizer
+
+from accelerate.utils import compute_module_sizes
+
+
+DEFAULT_MODELS = {
+ "gpt-j-6b": {"is_causal": True, "model": "sgugger/sharded-gpt-j-6B", "tokenizer": "EleutherAI/gpt-j-6B"},
+ "gpt-neox": {"is_causal": True, "model": "EleutherAI/gpt-neox-20b"},
+ "opt": {"is_causal": True, "model": "facebook/opt-30b"},
+ "T0pp": {"is_causal": False, "model": "bigscience/T0pp", "model_revision": "sharded"},
+}
+
+PROMPTS = [
+ "Hello, my name is",
+ "Are unicorns real? Unicorns are",
+ "For the first time in several years,",
+ "My name is Julien and I am",
+ "The goal of life is",
+ "Whenever I'm sad, I like to",
+]
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Run and time generations on a big model using Accelerate.")
+ parser.add_argument("model_name", type=str, default=None, help="The name of the model to try.")
+ parser.add_argument(
+ "--tokenizer_name", type=str, default=None, help="The name of the tokenizer (if different from the model."
+ )
+ parser.add_argument("--is_causal", type=bool, default=None, help="Whether or not the model is causal.")
+ parser.add_argument(
+ "--model_revision", type=str, default=None, help="The revision to use for the model checkpoint."
+ )
+ parser.add_argument("--torch_dtype", type=str, default=None, help="The dtype for the model.")
+ parser.add_argument("--disk_offload", action="store_true")
+
+ args = parser.parse_args()
+
+ # Sanitize args
+ if args.model_name in DEFAULT_MODELS:
+ defaults = DEFAULT_MODELS[args.model_name]
+ args.model_name = defaults["model"]
+ if args.tokenizer_name is None:
+ args.tokenizer_name = defaults.get("tokenizer", args.model_name)
+ if args.is_causal is None:
+ args.is_causal = defaults["is_causal"]
+ if args.model_revision is None:
+ args.model_revision = defaults.get("model_revision", "main")
+
+ if args.is_causal is None:
+ raise ValueError("Could not infer the default for `--is_causal`, pass either True or False for it.")
+ if args.tokenizer_name is None:
+ args.tokenizer_name = args.model_name
+ if args.model_revision is None:
+ args.model_revision = "main"
+
+ return args
+
+
+def main():
+ transformers.utils.logging.set_verbosity_error()
+ args = parse_args()
+
+ if args.torch_dtype is None:
+ config = AutoConfig.from_pretrained(args.model_name)
+ torch_dtype = getattr(config, "torch_dtype", torch.float32)
+ else:
+ torch_dtype = getattr(torch, args.torch_dtype)
+ model_cls = AutoModelForCausalLM if args.is_causal else AutoModelForSeq2SeqLM
+ kwargs = {
+ "torch_dtype": torch_dtype,
+ "revision": args.model_revision,
+ }
+ if args.disk_offload:
+ kwargs["offload_folder"] = "tmp_offload"
+ kwargs["offload_state_dict"] = True
+
+ start_measures = start_measure()
+ model = model_cls.from_pretrained(args.model_name, device_map="auto", **kwargs)
+ end_measures = end_measure(start_measures)
+ log_measures(end_measures, "Model loading")
+
+ module_sizes = compute_module_sizes(model)
+ device_size = {v: 0 for v in model.hf_device_map.values()}
+ for module, device in model.hf_device_map.items():
+ device_size[device] += module_sizes[module]
+ message = "\n".join([f"- {device}: {size // 2**20}MiB" for device, size in device_size.items()])
+ print(f"\nTheoretical use:\n{message}")
+
+ tokenizer = AutoTokenizer.from_pretrained(args.tokenizer_name)
+
+ start_measures = start_measure()
+ generation_times = []
+ gen_tokens = []
+ texts_outs = []
+ for prompt in PROMPTS:
+ inputs = tokenizer(prompt, return_tensors="pt").to(0)
+ tokens = inputs["input_ids"][0].tolist()
+ before_generate = time.time()
+ outputs = model.generate(inputs["input_ids"])
+ after_generate = time.time()
+ outputs = outputs[0].tolist()
+ num_gen_tokens = len(outputs) if outputs[: len(tokens)] != tokens else len(outputs) - len(tokens)
+ generation_time = after_generate - before_generate
+
+ text_out = tokenizer.decode(outputs, skip_special_tokens=True)
+ texts_outs.append(text_out)
+ generation_times.append(generation_time)
+ gen_tokens.append(num_gen_tokens)
+ print(f"Prompt: {prompt}\nGeneration {text_out}\nIn {generation_time:.2f}s for {num_gen_tokens} tokens\n")
+
+ end_measures = end_measure(start_measures)
+ log_measures(end_measures, "Model generation")
+
+ generation_times_per_token = [gen / tok for gen, tok in zip(generation_times, gen_tokens)]
+ avg_gen = sum(generation_times_per_token) / len(generation_times)
+ print(f"Average time of generation per token: {avg_gen:.2f}s")
+ print(f"First generation (avg time per token): {generation_times_per_token[0]:.2f}s")
+ avg_gen = sum(generation_times_per_token[1:]) / (len(generation_times_per_token) - 1)
+ print(f"Average time of generation per token (excluding the first): {avg_gen:.2f}s")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/big_model_inference/measures_util.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/big_model_inference/measures_util.py
new file mode 100644
index 0000000000000000000000000000000000000000..00fb0dbfb85d38c0db05bba2196a9f9447dc77d6
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/big_model_inference/measures_util.py
@@ -0,0 +1,104 @@
+# Copyright 2023 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import gc
+import threading
+import time
+
+import psutil
+import torch
+
+from accelerate.test_utils.testing import get_backend
+
+
+torch_device_type, _, _ = get_backend()
+torch_accelerator_module = getattr(torch, torch_device_type, torch.cuda)
+
+
+class PeakCPUMemory:
+ def __init__(self):
+ self.process = psutil.Process()
+ self.peak_monitoring = False
+
+ def peak_monitor(self):
+ self.cpu_memory_peak = -1
+
+ while True:
+ self.cpu_memory_peak = max(self.process.memory_info().rss, self.cpu_memory_peak)
+
+ # can't sleep or will not catch the peak right (this comment is here on purpose)
+ if not self.peak_monitoring:
+ break
+
+ def start(self):
+ self.peak_monitoring = True
+ self.thread = threading.Thread(target=self.peak_monitor)
+ self.thread.daemon = True
+ self.thread.start()
+
+ def stop(self):
+ self.peak_monitoring = False
+ self.thread.join()
+ return self.cpu_memory_peak
+
+
+cpu_peak_tracker = PeakCPUMemory()
+
+
+def start_measure():
+ # Time
+ measures = {"time": time.time()}
+
+ gc.collect()
+ torch_accelerator_module.empty_cache()
+
+ # CPU mem
+ measures["cpu"] = psutil.Process().memory_info().rss
+ cpu_peak_tracker.start()
+
+ # GPU mem
+ for i in range(torch_accelerator_module.device_count()):
+ measures[str(i)] = torch_accelerator_module.memory_allocated(i)
+ torch_accelerator_module.reset_peak_memory_stats()
+
+ return measures
+
+
+def end_measure(start_measures):
+ # Time
+ measures = {"time": time.time() - start_measures["time"]}
+
+ gc.collect()
+ torch_accelerator_module.empty_cache()
+
+ # CPU mem
+ measures["cpu"] = (psutil.Process().memory_info().rss - start_measures["cpu"]) / 2**20
+ measures["cpu-peak"] = (cpu_peak_tracker.stop() - start_measures["cpu"]) / 2**20
+
+ # GPU mem
+ for i in range(torch_accelerator_module.device_count()):
+ measures[str(i)] = (torch_accelerator_module.memory_allocated(i) - start_measures[str(i)]) / 2**20
+ measures[f"{i}-peak"] = (torch_accelerator_module.max_memory_allocated(i) - start_measures[str(i)]) / 2**20
+
+ return measures
+
+
+def log_measures(measures, description):
+ print(f"{description}:")
+ print(f"- Time: {measures['time']:.2f}s")
+ for i in range(torch_accelerator_module.device_count()):
+ print(f"- {torch_device_type} {i} allocated: {measures[str(i)]:.2f}MiB")
+ peak = measures[f"{i}-peak"]
+ print(f"- {torch_device_type} {i} peak: {peak:.2f}MiB")
+ print(f"- CPU RAM allocated: {measures['cpu']:.2f}MiB")
+ print(f"- CPU RAM peak: {measures['cpu-peak']:.2f}MiB")
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/ms_amp/Dockerfile b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/ms_amp/Dockerfile
new file mode 100644
index 0000000000000000000000000000000000000000..4d7778200a52b9a5bbf33979bbb3cd34090854dd
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/ms_amp/Dockerfile
@@ -0,0 +1,12 @@
+FROM ghcr.io/azure/msamp
+
+RUN pip install transformers evaluate datasets
+RUN git clone https://github.com/huggingface/accelerate
+
+RUN cd accelerate && \
+ pip install -e . && \
+ cd benchmarks/fp8
+
+CMD ["bash"]
+
+
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/ms_amp/ddp.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/ms_amp/ddp.py
new file mode 100644
index 0000000000000000000000000000000000000000..942c3c6cf4ea34680c3fec3a2e4e2bdf5ebc8fd8
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/ms_amp/ddp.py
@@ -0,0 +1,123 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+This script tests to ensure that `accelerate` performs at the same level as raw `MS-AMP`.
+
+This particular script verifies this for DDP training.
+"""
+
+import evaluate
+import msamp
+import torch
+from fp8_utils import evaluate_model, get_training_utilities
+from torch.nn.parallel import DistributedDataParallel as DDP
+
+from accelerate import Accelerator
+from accelerate.state import AcceleratorState
+from accelerate.utils import FP8RecipeKwargs, get_grad_scaler, set_seed
+
+
+MODEL_NAME = "bert-base-cased"
+METRIC = evaluate.load("glue", "mrpc")
+
+
+def train_baseline(opt_level="O2"):
+ set_seed(42)
+ scaler = get_grad_scaler()
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(MODEL_NAME)
+ accelerator = Accelerator()
+ device = accelerator.device
+
+ model, optimizer = msamp.initialize(model, optimizer, opt_level=opt_level)
+
+ model.to(device)
+
+ # Convert the model to DDP
+ device_ids, output_device = [accelerator.local_process_index], accelerator.local_process_index
+ model = DDP(model, device_ids=device_ids, output_device=output_device)
+
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+
+ for i, batch in enumerate(train_dataloader):
+ with torch.autocast(device_type="cuda", dtype=torch.bfloat16):
+ outputs = model(**batch)
+ loss = outputs.loss
+ scaler.scale(loss).backward()
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+def train_integration(opt_level="O2"):
+ kwargs_handlers = [FP8RecipeKwargs(backend="msamp", opt_level=opt_level)]
+ AcceleratorState()._reset_state(True)
+ accelerator = Accelerator(mixed_precision="fp8", kwargs_handlers=kwargs_handlers)
+ set_seed(42)
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(
+ MODEL_NAME, accelerator=accelerator
+ )
+
+ model, optimizer = accelerator.prepare(model, optimizer)
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+ for i, batch in enumerate(train_dataloader):
+ with torch.autocast(device_type="cuda", dtype=torch.bfloat16):
+ outputs = model(**batch)
+ loss = outputs.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+if __name__ == "__main__":
+ for opt_level in ["O1", "O2"]:
+ baseline_not_trained, baseline_trained = train_baseline(opt_level)
+ accelerator_not_trained, accelerator_trained = train_integration(opt_level)
+ assert baseline_not_trained["accuracy"] == accelerator_not_trained["accuracy"], (
+ f"Accuracy not the same for untrained baseline and accelerator using opt_level={opt_level}: {baseline_not_trained['accuracy']} == {accelerator_not_trained['accuracy']}"
+ )
+ assert baseline_not_trained["f1"] == accelerator_not_trained["f1"], (
+ f"F1 not the same for untrained baseline and accelerator using opt_level={opt_level}: {baseline_not_trained['f1']} == {accelerator_not_trained['f1']}"
+ )
+ assert baseline_trained["accuracy"] == accelerator_trained["accuracy"], (
+ f"Accuracy not the same for trained baseline and accelerator using opt_level={opt_level}: {baseline_trained['accuracy']} == {accelerator_trained['accuracy']}"
+ )
+ assert baseline_trained["f1"] == accelerator_trained["f1"], (
+ f"F1 not the same for trained baseline and accelerator using opt_level={opt_level}: {baseline_trained['f1']} == {accelerator_trained['f1']}"
+ )
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/ms_amp/distrib_deepspeed.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/ms_amp/distrib_deepspeed.py
new file mode 100644
index 0000000000000000000000000000000000000000..a6bb268868c459cc7e50a353fa100e5e4a685c3b
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/ms_amp/distrib_deepspeed.py
@@ -0,0 +1,161 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+This script tests to ensure that `accelerate` performs at the same level as raw `MS-AMP`.
+
+This particular script verifies this for DeepSpeed training.
+
+NOTE: MS-AMP does *not* support ZeRO-3.
+"""
+
+# import msamp.deepspeed as msamp_deepspeed
+import evaluate
+import torch
+from fp8_utils import evaluate_model, get_training_utilities
+from msamp import deepspeed as msamp_deepspeed
+
+from accelerate import Accelerator, DeepSpeedPlugin
+from accelerate.state import AcceleratorState
+from accelerate.utils import set_seed
+
+
+MODEL_NAME = "bert-base-cased"
+METRIC = evaluate.load("glue", "mrpc")
+
+
+def train_baseline(zero_stage: int = 1, opt_level: str = "O1"):
+ set_seed(42)
+ accelerator = Accelerator()
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(
+ MODEL_NAME, accelerator=accelerator
+ )
+
+ import numpy as np
+
+ config = {
+ "train_batch_size": 32,
+ "train_micro_batch_size_per_gpu": 16,
+ "gradient_accumulation_steps": 1,
+ "zero_optimization": {
+ "stage": zero_stage,
+ "offload_optimizer": {"device": "none", "nvme_path": None},
+ "offload_param": {"device": "none", "nvme_path": None},
+ },
+ "gradient_clipping": 1.0,
+ "steps_per_print": np.inf,
+ "bf16": {"enabled": True},
+ "fp16": {"enabled": False},
+ "zero_allow_untested_optimizer": True,
+ "msamp": {
+ "enabled": True,
+ "opt_level": opt_level,
+ },
+ }
+ (
+ model,
+ optimizer,
+ _,
+ _,
+ ) = msamp_deepspeed.initialize(
+ model=model,
+ optimizer=optimizer,
+ config_params=config,
+ )
+
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+
+ for _ in range(2):
+ for batch in train_dataloader:
+ outputs = model(**batch)
+ loss = outputs.loss
+ model.backward(loss)
+ model.step()
+ for _ in range(accelerator.num_processes):
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.destroy()
+ torch.cuda.empty_cache()
+ AcceleratorState()._reset_state(True)
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+def train_integration(zero_stage: int = 1, opt_level: str = "O1"):
+ set_seed(42)
+ deepspeed_plugin = DeepSpeedPlugin(
+ zero_stage=zero_stage,
+ enable_msamp=True,
+ msamp_opt_level=opt_level,
+ )
+ accelerator = Accelerator(mixed_precision="fp8", deepspeed_plugin=deepspeed_plugin)
+ accelerator.state.deepspeed_plugin.deepspeed_config["train_micro_batch_size_per_gpu"] = 16
+
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(
+ MODEL_NAME, accelerator=accelerator
+ )
+
+ model, optimizer, lr_scheduler = accelerator.prepare(model, optimizer, lr_scheduler)
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+ for _ in range(2):
+ for batch in train_dataloader:
+ outputs = model(**batch)
+ loss = outputs.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.destroy()
+ torch.cuda.empty_cache()
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ AcceleratorState()._reset_state(True)
+ return base_model_results, trained_model_results
+
+
+if __name__ == "__main__":
+ for zero_stage in [1, 2]:
+ for opt_level in ["O1", "O2", "O3"]:
+ baseline_not_trained, baseline_trained = train_baseline(zero_stage, opt_level)
+ accelerator_not_trained, accelerator_trained = train_integration(zero_stage, opt_level)
+ assert baseline_not_trained["accuracy"] == accelerator_not_trained["accuracy"], (
+ f"ZERO stage {zero_stage}, opt_level={opt_level}:\nAccuracy should be the same for the baseline and accelerator: {baseline_not_trained['accuracy']} == {accelerator_not_trained['accuracy']}"
+ )
+ assert baseline_not_trained["f1"] == accelerator_not_trained["f1"], (
+ f"ZERO stage {zero_stage}, opt_level={opt_level}:\nF1 score should be the same for the baseline and accelerator: {baseline_not_trained['f1']} == {accelerator_not_trained['f1']}"
+ )
+ assert baseline_trained["accuracy"] == accelerator_trained["accuracy"], (
+ f"ZERO stage {zero_stage}, opt_level={opt_level}:\nAccuracy should be the same for the baseline and accelerator: {baseline_trained['accuracy']} == {accelerator_trained['accuracy']}"
+ )
+ assert baseline_trained["f1"] == accelerator_trained["f1"], (
+ f"ZERO stage {zero_stage}, opt_level={opt_level}:\nF1 score should be the same for the baseline and accelerator: {baseline_trained['f1']} == {accelerator_trained['f1']}"
+ )
+
+ torch.distributed.destroy_process_group()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/ms_amp/fp8_utils.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/ms_amp/fp8_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..602ce07fdc62b39c60b2dd62cf8a0fe2e085a308
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/ms_amp/fp8_utils.py
@@ -0,0 +1,118 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import torch
+
+
+def get_dataloaders(model_name: str, batch_size: int = 16):
+ from datasets import load_dataset
+ from torch.utils.data import DataLoader
+ from transformers import AutoTokenizer
+
+ tokenizer = AutoTokenizer.from_pretrained(model_name)
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ pad_to_multiple_of=16, # Specific for FP8
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size, drop_last=True
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"],
+ shuffle=False,
+ collate_fn=collate_fn,
+ batch_size=16,
+ drop_last=True,
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+def get_training_utilities(model_name: str, batch_size: int = 16, accelerator=None):
+ """
+ Returns a tuple of:
+ - Model
+ - Optimizer
+ - Train dataloader (prepared)
+ - Eval dataloader (prepared)
+ - LR Scheduler
+ Suitable for training on the MRPC dataset
+ """
+ from torch.optim import AdamW
+ from transformers import AutoModelForSequenceClassification, get_linear_schedule_with_warmup
+
+ from accelerate import Accelerator
+
+ if accelerator is None:
+ accelerator = Accelerator()
+ model = AutoModelForSequenceClassification.from_pretrained(model_name)
+ train_dataloader, eval_dataloader = get_dataloaders(model_name, batch_size)
+ optimizer = AdamW(model.parameters(), lr=0.0001)
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=100,
+ num_training_steps=len(train_dataloader) * 2,
+ )
+ train_dataloader, eval_dataloader = accelerator.prepare(train_dataloader, eval_dataloader)
+ return model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+
+
+def get_named_parameters(model):
+ """
+ Same thing as `Accelerator.get_named_parameters` Returns a list of the named parameters of the model (extracted
+ from parallel)
+ """
+ from accelerate.utils import extract_model_from_parallel
+
+ model = extract_model_from_parallel(model)
+ return {n: p for n, p in model.named_parameters()}
+
+
+def evaluate_model(model, dataloader, metric, accelerator=None):
+ "Turns model to .eval(), runs dataloader, calculates metric, then turns eval back on"
+ model.eval()
+ for step, batch in enumerate(dataloader):
+ with torch.no_grad():
+ # W/ MS-AMP, we need to cast while evaluating
+ with torch.autocast(device_type="cuda", dtype=torch.bfloat16):
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ references = batch["labels"]
+ if accelerator is not None and accelerator.num_processes > 1:
+ predictions, references = accelerator.gather_for_metrics((predictions, references))
+ metric.add_batch(predictions=predictions, references=references)
+ return metric.compute()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/ms_amp/non_distributed.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/ms_amp/non_distributed.py
new file mode 100644
index 0000000000000000000000000000000000000000..dc45aa452f88df9e737c59e8c498607544d5b0fb
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/ms_amp/non_distributed.py
@@ -0,0 +1,118 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+This script tests to ensure that `accelerate` performs at the same level as raw `MS-AMP`.
+
+This particular script verifies this for single GPU training.
+"""
+
+import evaluate
+import msamp
+import torch
+from fp8_utils import evaluate_model, get_training_utilities
+
+from accelerate import Accelerator
+from accelerate.state import AcceleratorState
+from accelerate.utils import FP8RecipeKwargs, get_grad_scaler, set_seed
+
+
+MODEL_NAME = "bert-base-cased"
+METRIC = evaluate.load("glue", "mrpc")
+
+
+def train_baseline(opt_level="O2"):
+ set_seed(42)
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(MODEL_NAME)
+
+ model, optimizer = msamp.initialize(model, optimizer, opt_level=opt_level)
+ model.to("cuda")
+
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC)
+ model.train()
+ scaler = get_grad_scaler()
+
+ for batch in train_dataloader:
+ batch = batch.to("cuda")
+ with torch.autocast(device_type="cuda", dtype=torch.bfloat16):
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss = scaler.scale(loss)
+ loss.backward()
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+def train_integration(opt_level="O2"):
+ kwargs_handlers = [FP8RecipeKwargs(backend="msamp", opt_level=opt_level)]
+ AcceleratorState()._reset_state(True)
+ accelerator = Accelerator(mixed_precision="fp8", kwargs_handlers=kwargs_handlers)
+ set_seed(42)
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(
+ MODEL_NAME, accelerator=accelerator
+ )
+
+ model, optimizer, lr_scheduler = accelerator.prepare(model, optimizer, lr_scheduler)
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC)
+ model.train()
+
+ for batch in train_dataloader:
+ outputs = model(**batch)
+ loss = outputs.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+if __name__ == "__main__":
+ for opt_level in ["O1", "O2"]:
+ baseline_not_trained, baseline_trained = train_baseline(opt_level)
+ accelerator_not_trained, accelerator_trained = train_integration(opt_level)
+
+ assert baseline_not_trained["accuracy"] == accelerator_not_trained["accuracy"], (
+ f"Accuracy should be the same for the baseline and accelerator: {baseline_not_trained['accuracy']} == {accelerator_not_trained['accuracy']}"
+ )
+ assert baseline_not_trained["f1"] == accelerator_not_trained["f1"], (
+ f"F1 score should be the same for the baseline and accelerator: {baseline_not_trained['f1']} == {accelerator_not_trained['f1']}"
+ )
+ assert baseline_trained["accuracy"] == accelerator_trained["accuracy"], (
+ f"Accuracy should be the same for the baseline and accelerator: {baseline_trained['accuracy']} == {accelerator_trained['accuracy']}"
+ )
+ assert baseline_trained["f1"] == accelerator_trained["f1"], (
+ f"F1 score should be the same for the baseline and accelerator: {baseline_trained['f1']} == {accelerator_trained['f1']}"
+ )
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/Dockerfile b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/Dockerfile
new file mode 100644
index 0000000000000000000000000000000000000000..88c21934d4eb435565916376997fe16811057fb6
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/Dockerfile
@@ -0,0 +1,12 @@
+FROM nvcr.io/nvidia/pytorch:24.07-py3
+
+RUN pip install transformers evaluate datasets
+RUN git clone https://github.com/huggingface/accelerate.git
+
+RUN cd accelerate && \
+ pip install -e . && \
+ cd benchmarks/fp8
+
+RUN /bin/bash
+
+
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/README.md b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..d5abadaf64ed7702677770ae6c18270c214d4a46
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/README.md
@@ -0,0 +1,32 @@
+# FP8 Benchmarks
+
+Comparing and running [torchao](https://github.com/pytorch/ao/tree/main/torchao/float8) FP8 with accelerate
+
+## Overview
+
+This repo provides scripts which compare native `torchao` model training against `accelerate`'s own integration. Each modeling type is segmented out via a script, supporting the following:
+
+* Single GPU training (`non_distributed.py`)
+* Multi-GPU training via DistributedDataParallelism (`ddp.py`)
+* Fully Sharded Data Parallelism (`fsdp.py`)
+* DeepSpeed ZeRO 1-3 (`deepspeed.py`)
+
+To run them, it's recommended to use a docker image (see the attached `Dockerfile`) and not install `torchao` manually.
+
+## Running:
+
+There are official Docker images located at `huggingface/accelerate:gpu-fp8-torchao-nightly` which can be used.
+
+You can run all scripts using the core `accelerate launch` command without any `accelerate config` being needed.
+
+For single GPU, run it via `python`:
+
+```bash
+python non_distributed.py
+```
+
+For the rest, run it via `accelerate launch`:
+
+```bash
+accelerate launch ddp.py # or distrib_deepspeed.py, ddp.py
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/ddp.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/ddp.py
new file mode 100644
index 0000000000000000000000000000000000000000..13b551abd05a8e600d34a3e5699a45373fb4a731
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/ddp.py
@@ -0,0 +1,158 @@
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+This script tests to ensure that `accelerate` performs at the same level as raw `torchao`.
+
+This particular script verifies this for DDP training.
+"""
+
+from functools import partial
+
+import evaluate
+import torch
+from fp8_utils import get_training_utilities
+from torch.nn.parallel import DistributedDataParallel as DDP
+from torchao.float8 import convert_to_float8_training
+
+from accelerate import Accelerator
+from accelerate.state import AcceleratorState
+from accelerate.utils import AORecipeKwargs, set_seed
+
+
+MODEL_NAME = "bert-base-cased"
+METRIC = evaluate.load("glue", "mrpc")
+
+
+def evaluate_model(model, dataloader, metric, accelerator=None):
+ "Turns model to .eval(), runs dataloader, calculates metric, then turns eval back on"
+ model.eval()
+ for step, batch in enumerate(dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ references = batch["labels"]
+ if accelerator is not None and accelerator.num_processes > 1:
+ predictions, references = accelerator.gather_for_metrics((predictions, references))
+ metric.add_batch(predictions=predictions, references=references)
+ return metric.compute()
+
+
+def filter_linear_layers(module, fqn, first_layer_name=None, last_layer_name=None):
+ if isinstance(module, torch.nn.Linear):
+ if module.in_features % 16 != 0 or module.out_features % 16 != 0:
+ return False
+ # For stability reasons, we skip the first and last linear layers
+ # Otherwise can lead to the model not training or converging properly
+ if fqn in (first_layer_name, last_layer_name):
+ return False
+ return True
+
+
+def train_baseline():
+ set_seed(42)
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(MODEL_NAME)
+ first_linear = None
+ last_linear = None
+ for name, module in model.named_modules():
+ if isinstance(module, torch.nn.Linear):
+ if first_linear is None:
+ first_linear = name
+ last_linear = name
+ func = partial(filter_linear_layers, first_layer_name=first_linear, last_layer_name=last_linear)
+ accelerator = Accelerator()
+ device = accelerator.device
+ model.to(device)
+
+ convert_to_float8_training(model, module_filter_fn=func)
+
+ # Convert the model to DDP
+ device_ids, output_device = [accelerator.local_process_index], accelerator.local_process_index
+ model = DDP(model, device_ids=device_ids, output_device=output_device)
+
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+
+ for batch in train_dataloader:
+ with torch.autocast(device_type="cuda", dtype=torch.bfloat16):
+ batch = batch.to(device)
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss.backward()
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+def train_integration():
+ AcceleratorState()._reset_state(True)
+ accelerator = Accelerator(mixed_precision="fp8", kwargs_handlers=[AORecipeKwargs()])
+ set_seed(42)
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(
+ MODEL_NAME, accelerator=accelerator
+ )
+
+ model, optimizer = accelerator.prepare(model, optimizer)
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+
+ for batch in train_dataloader:
+ outputs = model(**batch)
+ loss = outputs.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+if __name__ == "__main__":
+ baseline_not_trained, baseline_trained = train_baseline()
+ accelerator_not_trained, accelerator_trained = train_integration()
+
+ assert baseline_not_trained["accuracy"] == accelerator_not_trained["accuracy"], (
+ f"Accuracy should be the same for the baseline and accelerator: {baseline_not_trained['accuracy']} == {accelerator_not_trained['accuracy']}"
+ )
+ assert baseline_not_trained["f1"] == accelerator_not_trained["f1"], (
+ f"F1 score should be the same for the baseline and accelerator: {baseline_not_trained['f1']} == {accelerator_not_trained['f1']}"
+ )
+ assert baseline_trained["accuracy"] == accelerator_trained["accuracy"], (
+ f"Accuracy should be the same for the baseline and accelerator: {baseline_trained['accuracy']} == {accelerator_trained['accuracy']}"
+ )
+ assert baseline_trained["f1"] == accelerator_trained["f1"], (
+ f"F1 score should be the same for the baseline and accelerator: {baseline_trained['f1']} == {accelerator_trained['f1']}"
+ )
+
+ torch.distributed.destroy_process_group()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/distrib_deepspeed.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/distrib_deepspeed.py
new file mode 100644
index 0000000000000000000000000000000000000000..f76d1c668f82e22a48f6ae3454fd79a129d17f4c
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/distrib_deepspeed.py
@@ -0,0 +1,213 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+This script tests to ensure that `accelerate` performs at the same level as raw `torchao`.
+
+This particular script verifies this for deepspeed training.
+"""
+
+from functools import partial
+from unittest.mock import patch
+
+import deepspeed
+import evaluate
+import torch
+from fp8_utils import evaluate_model, get_training_utilities
+from torchao.float8 import convert_to_float8_training
+from transformers.integrations import HfDeepSpeedConfig
+
+from accelerate import Accelerator, DeepSpeedPlugin
+from accelerate.state import AcceleratorState
+from accelerate.utils import AORecipeKwargs, set_seed
+
+
+MODEL_NAME = "bert-base-cased"
+METRIC = evaluate.load("glue", "mrpc")
+
+
+def filter_linear_layers(module, fqn, first_layer_name=None, last_layer_name=None):
+ if isinstance(module, torch.nn.Linear):
+ if module.in_features % 16 != 0 or module.out_features % 16 != 0:
+ return False
+ # For stability reasons, we skip the first and last linear layers
+ # Otherwise can lead to the model not training or converging properly
+ if fqn in (first_layer_name, last_layer_name):
+ return False
+ return True
+
+
+def train_baseline(zero_stage: int = 1):
+ set_seed(42)
+ # This forces transformers to think Zero-3 Init should be used
+ with patch("transformers.integrations.deepspeed.is_deepspeed_zero3_enabled") as mock:
+ mock.return_value = zero_stage == 3
+
+ config = HfDeepSpeedConfig(
+ {
+ "train_micro_batch_size_per_gpu": 16,
+ "gradient_accumulation_steps": 1,
+ "zero_optimization": {"stage": zero_stage},
+ }
+ )
+ plugin = DeepSpeedPlugin(hf_ds_config=config)
+ accelerator = Accelerator(deepspeed_plugin=plugin)
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(
+ MODEL_NAME, accelerator=accelerator
+ )
+ first_linear = None
+ last_linear = None
+ for name, module in model.named_modules():
+ if isinstance(module, torch.nn.Linear):
+ if first_linear is None:
+ first_linear = name
+ last_linear = name
+ func = partial(filter_linear_layers, first_layer_name=first_linear, last_layer_name=last_linear)
+
+ convert_to_float8_training(model, module_filter_fn=func)
+
+ import numpy as np
+
+ config = {
+ "train_batch_size": 32,
+ "train_micro_batch_size_per_gpu": 16,
+ "gradient_accumulation_steps": 1,
+ "zero_optimization": {
+ "stage": zero_stage,
+ "offload_optimizer": {"device": "none", "nvme_path": None},
+ "offload_param": {"device": "none", "nvme_path": None},
+ "stage3_gather_16bit_weights_on_model_save": False,
+ },
+ "gradient_clipping": 1.0,
+ "steps_per_print": np.inf,
+ "bf16": {"enabled": True},
+ "fp16": {"enabled": False},
+ "zero_allow_untested_optimizer": True,
+ }
+
+ (
+ model,
+ optimizer,
+ _,
+ lr_scheduler,
+ ) = deepspeed.initialize(
+ model=model,
+ optimizer=optimizer,
+ lr_scheduler=lr_scheduler,
+ config_params=config,
+ )
+
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+
+ model_outputs = []
+ data = []
+
+ for batch in train_dataloader:
+ outputs = model(**batch)
+ data.append(batch.to("cpu"))
+ model_outputs.append(outputs.logits.to("cpu"))
+ loss = outputs.loss
+ model.backward(loss)
+ model.step()
+ for _ in range(accelerator.num_processes):
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.destroy()
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ del config
+ return base_model_results, trained_model_results, model_outputs, data
+
+
+def train_integration(zero_stage: int = 1):
+ set_seed(42)
+ AcceleratorState()._reset_state(True)
+ config = HfDeepSpeedConfig(
+ {
+ "train_micro_batch_size_per_gpu": 16,
+ "gradient_accumulation_steps": 1,
+ "zero_optimization": {"stage": zero_stage},
+ }
+ )
+ deepspeed_plugin = DeepSpeedPlugin(
+ hf_ds_config=config,
+ )
+ # This forces transformers to think Zero-3 Init should be used
+ with patch("transformers.integrations.deepspeed.is_deepspeed_zero3_enabled") as mock:
+ mock.return_value = zero_stage == 3
+ accelerator = Accelerator(
+ mixed_precision="fp8", kwargs_handlers=[AORecipeKwargs()], deepspeed_plugin=deepspeed_plugin
+ )
+
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(
+ MODEL_NAME, accelerator=accelerator
+ )
+
+ model, optimizer, lr_scheduler, train_dataloader, eval_dataloader = accelerator.prepare(
+ model, optimizer, lr_scheduler, train_dataloader, eval_dataloader
+ )
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+ model_outputs = []
+ data = []
+ for batch in train_dataloader:
+ outputs = model(**batch)
+ data.append(batch.to("cpu"))
+ model_outputs.append(outputs.logits.to("cpu"))
+ loss = outputs.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.destroy()
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ del config
+ return base_model_results, trained_model_results, model_outputs, data
+
+
+if __name__ == "__main__":
+ for zero_stage in [1, 2, 3]:
+ baseline_not_trained, baseline_trained, baseline_outputs, baseline_data = train_baseline(zero_stage)
+ accelerator_not_trained, accelerator_trained, accelerator_outputs, accelerator_data = train_integration(
+ zero_stage
+ )
+ assert baseline_not_trained["accuracy"] == accelerator_not_trained["accuracy"], (
+ f"ZERO stage {zero_stage}: Accuracy should be the same for the baseline and accelerator: {baseline_not_trained['accuracy']} == {accelerator_not_trained['accuracy']}"
+ )
+ assert baseline_not_trained["f1"] == accelerator_not_trained["f1"], (
+ f"ZERO stage {zero_stage}: F1 score should be the same for the baseline and accelerator: {baseline_not_trained['f1']} == {accelerator_not_trained['f1']}"
+ )
+ assert baseline_trained["accuracy"] == accelerator_trained["accuracy"], (
+ f"ZERO stage {zero_stage}: Accuracy should be the same for the baseline and accelerator: {baseline_trained['accuracy']} == {accelerator_trained['accuracy']}"
+ )
+ assert baseline_trained["f1"] == accelerator_trained["f1"], (
+ f"ZERO stage {zero_stage}: F1 score should be the same for the baseline and accelerator: {baseline_trained['f1']} == {accelerator_trained['f1']}"
+ )
+ AcceleratorState()._reset_state(True)
+ torch.distributed.destroy_process_group()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/fp8_utils.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/fp8_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..1aaa7db5df999b89b503094a09c3ad60d6b03998
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/fp8_utils.py
@@ -0,0 +1,116 @@
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import torch
+
+
+def get_dataloaders(model_name: str, batch_size: int = 16):
+ from datasets import load_dataset
+ from torch.utils.data import DataLoader
+ from transformers import AutoTokenizer
+
+ tokenizer = AutoTokenizer.from_pretrained(model_name)
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ pad_to_multiple_of=16, # Specific for FP8
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size, drop_last=True
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"],
+ shuffle=False,
+ collate_fn=collate_fn,
+ batch_size=16,
+ drop_last=True,
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+def get_training_utilities(model_name: str, batch_size: int = 16, accelerator=None, prepare=True):
+ """
+ Returns a tuple of:
+ - Model
+ - Optimizer
+ - Train dataloader (prepared)
+ - Eval dataloader (prepared)
+ - LR Scheduler
+ Suitable for training on the MRPC dataset
+ """
+ from torch.optim import AdamW
+ from transformers import AutoModelForSequenceClassification, get_linear_schedule_with_warmup
+
+ from accelerate import Accelerator
+
+ if accelerator is None:
+ accelerator = Accelerator()
+ model = AutoModelForSequenceClassification.from_pretrained(model_name)
+ train_dataloader, eval_dataloader = get_dataloaders(model_name, batch_size)
+ optimizer = AdamW(model.parameters(), lr=0.0001)
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=100,
+ num_training_steps=len(train_dataloader) * 2,
+ )
+ train_dataloader, eval_dataloader = accelerator.prepare(train_dataloader, eval_dataloader)
+ return model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+
+
+def get_named_parameters(model):
+ """
+ Same thing as `Accelerator.get_named_parameters` Returns a list of the named parameters of the model (extracted
+ from parallel)
+ """
+ from accelerate.utils import extract_model_from_parallel
+
+ model = extract_model_from_parallel(model)
+ return {n: p for n, p in model.named_parameters()}
+
+
+def evaluate_model(model, dataloader, metric, accelerator=None):
+ "Turns model to .eval(), runs dataloader, calculates metric, then turns eval back on"
+ model.eval()
+ for step, batch in enumerate(dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ references = batch["labels"]
+ if accelerator is not None and accelerator.num_processes > 1:
+ predictions, references = accelerator.gather_for_metrics((predictions, references))
+ metric.add_batch(predictions=predictions, references=references)
+ return metric.compute()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/fsdp.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/fsdp.py
new file mode 100644
index 0000000000000000000000000000000000000000..fbac6e111a4fa450dbfedf5118726ab1a6a4d3d6
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/fsdp.py
@@ -0,0 +1,173 @@
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+This script tests to ensure that `accelerate` performs at the same level as raw `torchao`.
+
+This particular script verifies this for FSDP training.
+"""
+
+from functools import partial
+
+import evaluate
+import torch
+from fp8_utils import get_training_utilities
+from torch.distributed.fsdp import FullyShardedDataParallel as FSDP
+from torch.distributed.fsdp import MixedPrecision
+from torch.distributed.fsdp.wrap import transformer_auto_wrap_policy
+from torchao.float8 import convert_to_float8_training
+from transformers.models.bert import BertLayer
+
+from accelerate import Accelerator
+from accelerate import FullyShardedDataParallelPlugin as FSDPPlugin
+from accelerate.state import AcceleratorState
+from accelerate.utils import AORecipeKwargs, set_seed
+
+
+MODEL_NAME = "bert-base-cased"
+METRIC = evaluate.load("glue", "mrpc")
+
+FSDP_WRAP_POLICY = partial(transformer_auto_wrap_policy, transformer_layer_cls={BertLayer})
+
+
+def filter_linear_layers(module, fqn, first_layer_name=None, last_layer_name=None):
+ if isinstance(module, torch.nn.Linear):
+ if module.in_features % 16 != 0 or module.out_features % 16 != 0:
+ return False
+ # For stability reasons, we skip the first and last linear layers
+ # Otherwise can lead to the model not training or converging properly
+ if fqn in (first_layer_name, last_layer_name):
+ return False
+ return True
+
+
+def evaluate_model(model, dataloader, metric, accelerator=None):
+ "Turns model to .eval(), runs dataloader, calculates metric, then turns eval back on"
+ model.eval()
+ for step, batch in enumerate(dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ references = batch["labels"]
+ if accelerator is not None and accelerator.num_processes > 1:
+ predictions, references = accelerator.gather_for_metrics((predictions, references))
+ metric.add_batch(predictions=predictions, references=references)
+ return metric.compute()
+
+
+def train_baseline():
+ set_seed(42)
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(MODEL_NAME)
+ first_linear = None
+ last_linear = None
+ for name, module in model.named_modules():
+ if isinstance(module, torch.nn.Linear):
+ if first_linear is None:
+ first_linear = name
+ last_linear = name
+ func = partial(filter_linear_layers, first_layer_name=first_linear, last_layer_name=last_linear)
+ accelerator = Accelerator()
+ device = accelerator.device
+ model.to(device)
+
+ convert_to_float8_training(model, module_filter_fn=func)
+
+ # Convert the model to FSDP
+ model = FSDP(
+ model,
+ use_orig_params=True,
+ mixed_precision=MixedPrecision(param_dtype=torch.bfloat16, reduce_dtype=torch.float32),
+ auto_wrap_policy=FSDP_WRAP_POLICY,
+ )
+
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+
+ for batch in train_dataloader:
+ with torch.autocast(device_type="cuda", dtype=torch.bfloat16):
+ batch = batch.to(device)
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss.backward()
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+def train_integration():
+ AcceleratorState()._reset_state(True)
+ fsdp_plugin = FSDPPlugin(
+ auto_wrap_policy=FSDP_WRAP_POLICY,
+ use_orig_params=True,
+ mixed_precision_policy=MixedPrecision(param_dtype=torch.bfloat16, reduce_dtype=torch.float32),
+ )
+ accelerator = Accelerator(mixed_precision="fp8", fsdp_plugin=fsdp_plugin, kwargs_handlers=[AORecipeKwargs()])
+ set_seed(42)
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(
+ MODEL_NAME, accelerator=accelerator
+ )
+
+ model, optimizer = accelerator.prepare(model, optimizer)
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+
+ for batch in train_dataloader:
+ outputs = model(**batch)
+ loss = outputs.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+if __name__ == "__main__":
+ baseline_not_trained, baseline_trained = train_baseline()
+ accelerator_not_trained, accelerator_trained = train_integration()
+
+ assert baseline_not_trained["accuracy"] == accelerator_not_trained["accuracy"], (
+ f"Accuracy should be the same for the baseline and accelerator: {baseline_not_trained['accuracy']} == {accelerator_not_trained['accuracy']}"
+ )
+ assert baseline_not_trained["f1"] == accelerator_not_trained["f1"], (
+ f"F1 score should be the same for the baseline and accelerator: {baseline_not_trained['f1']} == {accelerator_not_trained['f1']}"
+ )
+ assert baseline_trained["accuracy"] == accelerator_trained["accuracy"], (
+ f"Accuracy should be the same for the baseline and accelerator: {baseline_trained['accuracy']} == {accelerator_trained['accuracy']}"
+ )
+ assert baseline_trained["f1"] == accelerator_trained["f1"], (
+ f"F1 score should be the same for the baseline and accelerator: {baseline_trained['f1']} == {accelerator_trained['f1']}"
+ )
+
+ torch.distributed.destroy_process_group()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/non_distributed.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/non_distributed.py
new file mode 100644
index 0000000000000000000000000000000000000000..621b87f30bd02a54c5f7fa5025c2951272f30e84
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/torchao/non_distributed.py
@@ -0,0 +1,145 @@
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+This script tests to ensure that `accelerate` performs at the same level as raw `torchao`.
+
+This particular script verifies this for single GPU training.
+"""
+
+from functools import partial
+
+import evaluate
+import torch
+from fp8_utils import get_training_utilities
+from torchao.float8 import convert_to_float8_training
+
+from accelerate import Accelerator
+from accelerate.state import AcceleratorState
+from accelerate.utils import AORecipeKwargs, set_seed
+
+
+MODEL_NAME = "bert-base-cased"
+METRIC = evaluate.load("glue", "mrpc")
+
+
+def evaluate_model(model, dataloader, metric, accelerator=None):
+ "Turns model to .eval(), runs dataloader, calculates metric, then turns eval back on"
+ model.eval()
+ for step, batch in enumerate(dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ references = batch["labels"]
+ if accelerator is not None and accelerator.num_processes > 1:
+ predictions, references = accelerator.gather_for_metrics((predictions, references))
+ metric.add_batch(predictions=predictions, references=references)
+ return metric.compute()
+
+
+def filter_linear_layers(module, fqn, first_layer_name=None, last_layer_name=None):
+ if isinstance(module, torch.nn.Linear):
+ if module.in_features % 16 != 0 or module.out_features % 16 != 0:
+ return False
+ # For stability reasons, we skip the first and last linear layers
+ # Otherwise can lead to the model not training or converging properly
+ if fqn in (first_layer_name, last_layer_name):
+ return False
+ return True
+
+
+def train_baseline():
+ set_seed(42)
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(MODEL_NAME)
+ first_linear = None
+ last_linear = None
+ for name, module in model.named_modules():
+ if isinstance(module, torch.nn.Linear):
+ if first_linear is None:
+ first_linear = name
+ last_linear = name
+
+ func = partial(filter_linear_layers, first_layer_name=first_linear, last_layer_name=last_linear)
+ model.to("cuda")
+ convert_to_float8_training(model, module_filter_fn=func)
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC)
+ model.train()
+
+ for batch in train_dataloader:
+ with torch.autocast(device_type="cuda", dtype=torch.bfloat16):
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss.backward()
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+def train_integration():
+ set_seed(42)
+ accelerator = Accelerator(mixed_precision="fp8", kwargs_handlers=[AORecipeKwargs()])
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(
+ MODEL_NAME, accelerator=accelerator
+ )
+ model = accelerator.prepare(model)
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC)
+ model.train()
+
+ for batch in train_dataloader:
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss.backward()
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+if __name__ == "__main__":
+ baseline_not_trained, baseline_trained = train_baseline()
+ AcceleratorState._reset_state(True)
+ accelerator_not_trained, accelerator_trained = train_integration()
+ assert baseline_not_trained["accuracy"] == accelerator_not_trained["accuracy"], (
+ f"Accuracy should be the same for the baseline and accelerator: {baseline_not_trained['accuracy']} == {accelerator_not_trained['accuracy']}"
+ )
+ assert baseline_not_trained["f1"] == accelerator_not_trained["f1"], (
+ f"F1 score should be the same for the baseline and accelerator: {baseline_not_trained['f1']} == {accelerator_not_trained['f1']}"
+ )
+ assert baseline_trained["accuracy"] == accelerator_trained["accuracy"], (
+ f"Accuracy should be the same for the baseline and accelerator: {baseline_trained['accuracy']} == {accelerator_trained['accuracy']}"
+ )
+ assert baseline_trained["f1"] == accelerator_trained["f1"], (
+ f"F1 score should be the same for the baseline and accelerator: {baseline_trained['f1']} == {accelerator_trained['f1']}"
+ )
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/Dockerfile b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/Dockerfile
new file mode 100644
index 0000000000000000000000000000000000000000..608b1a334523b24d2a78407f75a5cbffc07d548d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/Dockerfile
@@ -0,0 +1,15 @@
+ARG BASE_YEAR=25
+ARG BASE_MONTH=03
+
+FROM nvcr.io/nvidia/pytorch:${BASE_YEAR}.${BASE_MONTH}-py3
+
+RUN pip install transformers evaluate datasets
+RUN git clone https://github.com/huggingface/accelerate.git
+
+RUN cd accelerate && \
+ pip install -e .[deepspeed] && \
+ cd benchmarks/fp8
+
+RUN /bin/bash
+
+
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/README.md b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..71fb42dbdc192d4493d92c265fdaa62ec4eb5b34
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/README.md
@@ -0,0 +1,32 @@
+# FP8 Benchmarks
+
+Comparing and running [TransformerEngine](https://github.com/NVIDIA/TransformerEngine) FP8 with accelerate
+
+## Overview
+
+This repo provides scripts which compare native TransformerEngine model training against `accelerate`'s own integration. Each modeling type is segmented out via a script, supporting the following:
+
+* Single GPU training (`non_distributed.py`)
+* Multi-GPU training via DistributedDataParallelism (`ddp.py`)
+* Fully Sharded Data Parallelism (`fsdp.py`)
+* DeepSpeed ZeRO 1-3 (`deepspeed.py`)
+
+To run them, it's recommended to use a docker image (see the attached `Dockerfile`) and not install `TransformerEngine` manually.
+
+## Running:
+
+There are official Docker images located at `huggingface/accelerate:gpu-fp8-transformerengine-nightly` which can be used.
+
+You can run all scripts using the core `accelerate launch` command without any `accelerate config` being needed.
+
+For single GPU, run it via `python`:
+
+```bash
+python non_distributed.py
+```
+
+For the rest, run it via `accelerate launch`:
+
+```bash
+accelerate launch ddp.py # or distrib_deepspeed.py, ddp.py
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/ddp.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/ddp.py
new file mode 100644
index 0000000000000000000000000000000000000000..2cab285e1f842b9cc374e6d3ed5b1310acb6da30
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/ddp.py
@@ -0,0 +1,144 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+This script tests to ensure that `accelerate` performs at the same level as raw `TransformersEngine`.
+
+This particular script verifies this for DDP training.
+"""
+
+import evaluate
+import torch
+import transformer_engine.common.recipe as te_recipe
+import transformer_engine.pytorch as te
+from fp8_utils import evaluate_model, get_named_parameters, get_training_utilities
+from torch.nn.parallel import DistributedDataParallel as DDP
+from transformer_engine.common.recipe import DelayedScaling
+
+from accelerate import Accelerator
+from accelerate.state import AcceleratorState
+from accelerate.utils import FP8RecipeKwargs, set_seed
+from accelerate.utils.transformer_engine import convert_model
+
+
+MODEL_NAME = "bert-base-cased"
+METRIC = evaluate.load("glue", "mrpc")
+
+
+def train_baseline():
+ set_seed(42)
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(MODEL_NAME)
+ accelerator = Accelerator()
+ device = accelerator.device
+ model.to(device)
+
+ # Convert the model to TE
+ old_named_params = get_named_parameters(model)
+
+ with torch.no_grad():
+ convert_model(model)
+
+ FP8_RECIPE_KWARGS = {"fp8_format": te_recipe.Format.HYBRID, "amax_history_len": 32, "amax_compute_algo": "max"}
+ fp8_recipe = DelayedScaling(**FP8_RECIPE_KWARGS)
+
+ new_named_params = get_named_parameters(model)
+
+ # Convert the model to DDP
+ device_ids, output_device = [accelerator.local_process_index], accelerator.local_process_index
+ model = DDP(model, device_ids=device_ids, output_device=output_device)
+
+ mapping = {p: new_named_params[n] for n, p in old_named_params.items()}
+ for param_group in optimizer.param_groups:
+ param_group["params"] = [mapping[p] for p in param_group["params"]]
+
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+
+ for _ in range(2):
+ for batch in train_dataloader:
+ with te.fp8_autocast(enabled=True, fp8_recipe=fp8_recipe):
+ with torch.autocast(device_type="cuda", dtype=torch.bfloat16):
+ batch = batch.to(device)
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss.backward()
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+def train_integration():
+ FP8_RECIPE_KWARGS = {"fp8_format": "HYBRID", "amax_history_len": 32, "amax_compute_algo": "max"}
+ kwargs_handlers = [FP8RecipeKwargs(backend="TE", **FP8_RECIPE_KWARGS)]
+ AcceleratorState()._reset_state(True)
+ accelerator = Accelerator(mixed_precision="fp8", kwargs_handlers=kwargs_handlers)
+ set_seed(42)
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(
+ MODEL_NAME, accelerator=accelerator
+ )
+
+ model, optimizer = accelerator.prepare(model, optimizer)
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+
+ for _ in range(2):
+ for batch in train_dataloader:
+ outputs = model(**batch)
+ loss = outputs.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+if __name__ == "__main__":
+ baseline_not_trained, baseline_trained = train_baseline()
+ accelerator_not_trained, accelerator_trained = train_integration()
+
+ assert baseline_not_trained["accuracy"] == accelerator_not_trained["accuracy"], (
+ f"Accuracy should be the same for the baseline and accelerator: {baseline_not_trained['accuracy']} == {accelerator_not_trained['accuracy']}"
+ )
+ assert baseline_not_trained["f1"] == accelerator_not_trained["f1"], (
+ f"F1 score should be the same for the baseline and accelerator: {baseline_not_trained['f1']} == {accelerator_not_trained['f1']}"
+ )
+ assert baseline_trained["accuracy"] == accelerator_trained["accuracy"], (
+ f"Accuracy should be the same for the baseline and accelerator: {baseline_trained['accuracy']} == {accelerator_trained['accuracy']}"
+ )
+ assert baseline_trained["f1"] == accelerator_trained["f1"], (
+ f"F1 score should be the same for the baseline and accelerator: {baseline_trained['f1']} == {accelerator_trained['f1']}"
+ )
+
+ torch.distributed.destroy_process_group()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/distrib_deepspeed.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/distrib_deepspeed.py
new file mode 100644
index 0000000000000000000000000000000000000000..6d64bf4f29a4f28a9f69bc0b4b01467dd1775dee
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/distrib_deepspeed.py
@@ -0,0 +1,191 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+This script tests to ensure that `accelerate` performs at the same level as raw `TransformersEngine`.
+
+This particular script verifies this for DDP training.
+"""
+
+from unittest.mock import patch
+
+import deepspeed
+import evaluate
+import torch
+import transformer_engine.common.recipe as te_recipe
+import transformer_engine.pytorch as te
+from fp8_utils import evaluate_model, get_named_parameters, get_training_utilities
+from transformer_engine.common.recipe import DelayedScaling
+
+from accelerate import Accelerator, DeepSpeedPlugin
+from accelerate.state import AcceleratorState
+from accelerate.utils import FP8RecipeKwargs, set_seed
+from accelerate.utils.transformer_engine import convert_model
+
+
+MODEL_NAME = "bert-base-cased"
+METRIC = evaluate.load("glue", "mrpc")
+
+
+def train_baseline(zero_stage: int = 1):
+ # This forces transformers to think Zero-3 Init should be used
+ with patch("transformers.integrations.deepspeed.is_deepspeed_zero3_enabled") as mock:
+ mock.return_value = zero_stage == 3
+ set_seed(42)
+
+ accelerator = Accelerator()
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(
+ MODEL_NAME, accelerator=accelerator
+ )
+
+ # Convert the model to TE
+ old_named_params = get_named_parameters(model)
+
+ with torch.no_grad():
+ convert_model(model)
+ new_named_params = get_named_parameters(model)
+
+ mapping = {p: new_named_params[n] for n, p in old_named_params.items()}
+ for param_group in optimizer.param_groups:
+ param_group["params"] = [mapping[p] for p in param_group["params"]]
+
+ FP8_RECIPE_KWARGS = {"fp8_format": te_recipe.Format.HYBRID, "amax_history_len": 32, "amax_compute_algo": "max"}
+ fp8_recipe = DelayedScaling(**FP8_RECIPE_KWARGS)
+
+ import numpy as np
+
+ config = {
+ "train_batch_size": 16,
+ "train_micro_batch_size_per_gpu": 16,
+ "gradient_accumulation_steps": 1,
+ "zero_optimization": {
+ "stage": zero_stage,
+ "offload_optimizer": {"device": "none", "nvme_path": None},
+ "offload_param": {"device": "none", "nvme_path": None},
+ "stage3_gather_16bit_weights_on_model_save": False,
+ },
+ "gradient_clipping": 1.0,
+ "steps_per_print": np.inf,
+ "bf16": {"enabled": True},
+ "fp16": {"enabled": False},
+ "zero_allow_untested_optimizer": True,
+ }
+
+ (
+ model,
+ optimizer,
+ _,
+ _,
+ ) = deepspeed.initialize(
+ model=model,
+ optimizer=optimizer,
+ config_params=config,
+ )
+
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+
+ model_outputs = []
+ data = []
+
+ for _ in range(2):
+ for batch in train_dataloader:
+ with te.fp8_autocast(enabled=True, fp8_recipe=fp8_recipe):
+ outputs = model(**batch)
+ data.append(batch.to("cpu"))
+ model_outputs.append(outputs.logits.to("cpu"))
+ loss = outputs.loss
+ model.backward(loss)
+ model.step()
+ for _ in range(accelerator.num_processes):
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.destroy()
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results, model_outputs, data
+
+
+def train_integration(zero_stage: int = 1):
+ set_seed(42)
+ FP8_RECIPE_KWARGS = {"fp8_format": "HYBRID", "amax_history_len": 32, "amax_compute_algo": "max"}
+ kwargs_handlers = [FP8RecipeKwargs(backend="TE", **FP8_RECIPE_KWARGS)]
+ AcceleratorState()._reset_state(True)
+ deepspeed_plugin = DeepSpeedPlugin(
+ zero_stage=zero_stage,
+ zero3_init_flag=zero_stage == 3,
+ )
+ accelerator = Accelerator(
+ mixed_precision="fp8", kwargs_handlers=kwargs_handlers, deepspeed_plugin=deepspeed_plugin
+ )
+ accelerator.state.deepspeed_plugin.deepspeed_config["train_micro_batch_size_per_gpu"] = 16
+
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(
+ MODEL_NAME, accelerator=accelerator
+ )
+
+ model, optimizer, lr_scheduler = accelerator.prepare(model, optimizer, lr_scheduler)
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+ model_outputs = []
+ data = []
+ for _ in range(2):
+ for batch in train_dataloader:
+ outputs = model(**batch)
+ data.append(batch.to("cpu"))
+ model_outputs.append(outputs.logits.to("cpu"))
+ loss = outputs.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.destroy()
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results, model_outputs, data
+
+
+if __name__ == "__main__":
+ for zero_stage in [1, 2, 3]:
+ baseline_not_trained, baseline_trained, baseline_outputs, baseline_data = train_baseline(zero_stage)
+ accelerator_not_trained, accelerator_trained, accelerator_outputs, accelerator_data = train_integration(
+ zero_stage
+ )
+ assert baseline_not_trained["accuracy"] == accelerator_not_trained["accuracy"], (
+ f"ZERO stage {zero_stage}: Accuracy should be the same for the baseline and accelerator: {baseline_not_trained['accuracy']} == {accelerator_not_trained['accuracy']}"
+ )
+ assert baseline_not_trained["f1"] == accelerator_not_trained["f1"], (
+ f"ZERO stage {zero_stage}: F1 score should be the same for the baseline and accelerator: {baseline_not_trained['f1']} == {accelerator_not_trained['f1']}"
+ )
+ assert baseline_trained["accuracy"] == accelerator_trained["accuracy"], (
+ f"ZERO stage {zero_stage}: Accuracy should be the same for the baseline and accelerator: {baseline_trained['accuracy']} == {accelerator_trained['accuracy']}"
+ )
+ assert baseline_trained["f1"] == accelerator_trained["f1"], (
+ f"ZERO stage {zero_stage}: F1 score should be the same for the baseline and accelerator: {baseline_trained['f1']} == {accelerator_trained['f1']}"
+ )
+
+ torch.distributed.destroy_process_group()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/fp8_utils.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/fp8_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..d28702e05ff0bbd77d0a51428082336fb5314181
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/fp8_utils.py
@@ -0,0 +1,116 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import torch
+
+
+def get_dataloaders(model_name: str, batch_size: int = 16):
+ from datasets import load_dataset
+ from torch.utils.data import DataLoader
+ from transformers import AutoTokenizer
+
+ tokenizer = AutoTokenizer.from_pretrained(model_name)
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ pad_to_multiple_of=16, # Specific for FP8
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size, drop_last=True
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"],
+ shuffle=False,
+ collate_fn=collate_fn,
+ batch_size=16,
+ drop_last=True,
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+def get_training_utilities(model_name: str, batch_size: int = 16, accelerator=None):
+ """
+ Returns a tuple of:
+ - Model
+ - Optimizer
+ - Train dataloader (prepared)
+ - Eval dataloader (prepared)
+ - LR Scheduler
+ Suitable for training on the MRPC dataset
+ """
+ from torch.optim import AdamW
+ from transformers import AutoModelForSequenceClassification, get_linear_schedule_with_warmup
+
+ from accelerate import Accelerator
+
+ if accelerator is None:
+ accelerator = Accelerator()
+ model = AutoModelForSequenceClassification.from_pretrained(model_name)
+ train_dataloader, eval_dataloader = get_dataloaders(model_name, batch_size)
+ optimizer = AdamW(model.parameters(), lr=0.0001)
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=100,
+ num_training_steps=len(train_dataloader) * 2,
+ )
+ train_dataloader, eval_dataloader = accelerator.prepare(train_dataloader, eval_dataloader)
+ return model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+
+
+def get_named_parameters(model):
+ """
+ Same thing as `Accelerator.get_named_parameters` Returns a list of the named parameters of the model (extracted
+ from parallel)
+ """
+ from accelerate.utils import extract_model_from_parallel
+
+ model = extract_model_from_parallel(model)
+ return {n: p for n, p in model.named_parameters()}
+
+
+def evaluate_model(model, dataloader, metric, accelerator=None):
+ "Turns model to .eval(), runs dataloader, calculates metric, then turns eval back on"
+ model.eval()
+ for step, batch in enumerate(dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ references = batch["labels"]
+ if accelerator is not None and accelerator.num_processes > 1:
+ predictions, references = accelerator.gather_for_metrics((predictions, references))
+ metric.add_batch(predictions=predictions, references=references)
+ return metric.compute()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/fsdp.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/fsdp.py
new file mode 100644
index 0000000000000000000000000000000000000000..26aca70ac6cd2af49570cef55977e3694202d446
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/fsdp.py
@@ -0,0 +1,161 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+This script tests to ensure that `accelerate` performs at the same level as raw `TransformersEngine`.
+
+This particular script verifies this for FSDP training.
+"""
+
+from functools import partial
+
+import evaluate
+import torch
+import transformer_engine.common.recipe as te_recipe
+import transformer_engine.pytorch as te
+from fp8_utils import evaluate_model, get_named_parameters, get_training_utilities
+from torch.distributed.fsdp import FullyShardedDataParallel as FSDP
+from torch.distributed.fsdp import MixedPrecision
+from torch.distributed.fsdp.wrap import transformer_auto_wrap_policy
+from transformer_engine.common.recipe import DelayedScaling
+from transformers.models.bert import BertLayer
+
+from accelerate import Accelerator
+from accelerate import FullyShardedDataParallelPlugin as FSDPPlugin
+from accelerate.state import AcceleratorState
+from accelerate.utils import FP8RecipeKwargs, set_seed
+from accelerate.utils.transformer_engine import convert_model
+
+
+MODEL_NAME = "bert-base-cased"
+METRIC = evaluate.load("glue", "mrpc")
+
+FSDP_WRAP_POLICY = partial(transformer_auto_wrap_policy, transformer_layer_cls={BertLayer})
+
+
+def train_baseline():
+ set_seed(42)
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(MODEL_NAME)
+ accelerator = Accelerator()
+ device = accelerator.device
+ model.to(device)
+
+ # Convert the model to TE
+ old_named_params = get_named_parameters(model)
+
+ with torch.no_grad():
+ convert_model(model)
+
+ FP8_RECIPE_KWARGS = {"fp8_format": te_recipe.Format.HYBRID, "amax_history_len": 32, "amax_compute_algo": "max"}
+ fp8_recipe = DelayedScaling(**FP8_RECIPE_KWARGS)
+
+ new_named_params = get_named_parameters(model)
+
+ # Convert the model to FSDP
+ model = FSDP(
+ model,
+ use_orig_params=True,
+ mixed_precision=MixedPrecision(param_dtype=torch.bfloat16, reduce_dtype=torch.float32),
+ auto_wrap_policy=FSDP_WRAP_POLICY,
+ )
+
+ mapping = {p: new_named_params[n] for n, p in old_named_params.items()}
+ for param_group in optimizer.param_groups:
+ param_group["params"] = [mapping[p] for p in param_group["params"]]
+
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+
+ for _ in range(2):
+ for batch in train_dataloader:
+ with te.fp8_autocast(enabled=True, fp8_recipe=fp8_recipe):
+ with torch.autocast(device_type="cuda", dtype=torch.bfloat16):
+ batch = batch.to(device)
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss.backward()
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+def train_integration():
+ FP8_RECIPE_KWARGS = {"fp8_format": "HYBRID", "amax_history_len": 32, "amax_compute_algo": "max"}
+ kwargs_handlers = [FP8RecipeKwargs(backend="TE", **FP8_RECIPE_KWARGS)]
+ AcceleratorState()._reset_state(True)
+ fsdp_plugin = FSDPPlugin(
+ auto_wrap_policy=FSDP_WRAP_POLICY,
+ use_orig_params=True,
+ mixed_precision_policy=MixedPrecision(param_dtype=torch.bfloat16, reduce_dtype=torch.float32),
+ )
+ accelerator = Accelerator(mixed_precision="fp8", fsdp_plugin=fsdp_plugin, kwargs_handlers=kwargs_handlers)
+ set_seed(42)
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(
+ MODEL_NAME, accelerator=accelerator
+ )
+
+ model, optimizer = accelerator.prepare(model, optimizer)
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+ model.train()
+
+ for _ in range(2):
+ for batch in train_dataloader:
+ outputs = model(**batch)
+ loss = outputs.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC, accelerator=accelerator)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+if __name__ == "__main__":
+ baseline_not_trained, baseline_trained = train_baseline()
+ accelerator_not_trained, accelerator_trained = train_integration()
+
+ assert baseline_not_trained["accuracy"] == accelerator_not_trained["accuracy"], (
+ f"Accuracy should be the same for the baseline and accelerator: {baseline_not_trained['accuracy']} == {accelerator_not_trained['accuracy']}"
+ )
+ assert baseline_not_trained["f1"] == accelerator_not_trained["f1"], (
+ f"F1 score should be the same for the baseline and accelerator: {baseline_not_trained['f1']} == {accelerator_not_trained['f1']}"
+ )
+ assert baseline_trained["accuracy"] == accelerator_trained["accuracy"], (
+ f"Accuracy should be the same for the baseline and accelerator: {baseline_trained['accuracy']} == {accelerator_trained['accuracy']}"
+ )
+ assert baseline_trained["f1"] == accelerator_trained["f1"], (
+ f"F1 score should be the same for the baseline and accelerator: {baseline_trained['f1']} == {accelerator_trained['f1']}"
+ )
+
+ torch.distributed.destroy_process_group()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/non_distributed.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/non_distributed.py
new file mode 100644
index 0000000000000000000000000000000000000000..8d647bfd1f990ef9ff3a400cd668ef3209a53f3d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fp8/transformer_engine/non_distributed.py
@@ -0,0 +1,132 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+This script tests to ensure that `accelerate` performs at the same level as raw `TransformersEngine`.
+
+This particular script verifies this for single GPU training.
+"""
+
+import evaluate
+import torch
+import transformer_engine.common.recipe as te_recipe
+import transformer_engine.pytorch as te
+from fp8_utils import evaluate_model, get_named_parameters, get_training_utilities
+from transformer_engine.common.recipe import DelayedScaling
+
+from accelerate import Accelerator
+from accelerate.state import AcceleratorState
+from accelerate.utils import FP8RecipeKwargs, set_seed
+from accelerate.utils.transformer_engine import convert_model
+
+
+MODEL_NAME = "bert-base-cased"
+METRIC = evaluate.load("glue", "mrpc")
+
+
+def train_baseline():
+ set_seed(42)
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(MODEL_NAME)
+
+ # Convert the model to TE
+ old_named_params = get_named_parameters(model)
+
+ with torch.no_grad():
+ convert_model(model)
+
+ new_named_params = get_named_parameters(model)
+ mapping = {p: new_named_params[n] for n, p in old_named_params.items()}
+ for param_group in optimizer.param_groups:
+ param_group["params"] = [mapping[p] for p in param_group["params"]]
+
+ FP8_RECIPE_KWARGS = {"fp8_format": te_recipe.Format.HYBRID, "amax_history_len": 32, "amax_compute_algo": "max"}
+ fp8_recipe = DelayedScaling(**FP8_RECIPE_KWARGS)
+
+ model.to("cuda")
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC)
+ model.train()
+
+ for batch in train_dataloader:
+ with te.fp8_autocast(enabled=True, fp8_recipe=fp8_recipe):
+ with torch.autocast(device_type="cuda", dtype=torch.bfloat16):
+ batch = batch.to("cuda")
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss.backward()
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+def train_integration():
+ FP8_RECIPE_KWARGS = {"fp8_format": "HYBRID", "amax_history_len": 32, "amax_compute_algo": "max"}
+ kwargs_handlers = [FP8RecipeKwargs(backend="TE", **FP8_RECIPE_KWARGS)]
+ AcceleratorState()._reset_state(True)
+ accelerator = Accelerator(mixed_precision="fp8", kwargs_handlers=kwargs_handlers)
+ set_seed(42)
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = get_training_utilities(
+ MODEL_NAME, accelerator=accelerator
+ )
+
+ model, optimizer, lr_scheduler = accelerator.prepare(model, optimizer, lr_scheduler)
+ base_model_results = evaluate_model(model, eval_dataloader, METRIC)
+ model.train()
+
+ for batch in train_dataloader:
+ outputs = model(**batch)
+ loss = outputs.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ optimizer.zero_grad()
+ lr_scheduler.step()
+
+ trained_model_results = evaluate_model(model, eval_dataloader, METRIC)
+
+ assert trained_model_results["accuracy"] > base_model_results["accuracy"], (
+ f"Accuracy should be higher for the trained model: {trained_model_results['accuracy']} > {base_model_results['accuracy']}"
+ )
+ assert trained_model_results["f1"] > base_model_results["f1"], (
+ f"F1 score should be higher for the trained model: {trained_model_results['f1']} > {base_model_results['f1']}"
+ )
+
+ return base_model_results, trained_model_results
+
+
+if __name__ == "__main__":
+ baseline_not_trained, baseline_trained = train_baseline()
+ accelerator_not_trained, accelerator_trained = train_integration()
+
+ assert baseline_not_trained["accuracy"] == accelerator_not_trained["accuracy"], (
+ f"Accuracy should be the same for the baseline and accelerator: {baseline_not_trained['accuracy']} == {accelerator_not_trained['accuracy']}"
+ )
+ assert baseline_not_trained["f1"] == accelerator_not_trained["f1"], (
+ f"F1 score should be the same for the baseline and accelerator: {baseline_not_trained['f1']} == {accelerator_not_trained['f1']}"
+ )
+ assert baseline_trained["accuracy"] == accelerator_trained["accuracy"], (
+ f"Accuracy should be the same for the baseline and accelerator: {baseline_trained['accuracy']} == {accelerator_trained['accuracy']}"
+ )
+ assert baseline_trained["f1"] == accelerator_trained["f1"], (
+ f"F1 score should be the same for the baseline and accelerator: {baseline_trained['f1']} == {accelerator_trained['f1']}"
+ )
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/README.md b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..f1079d68e2f20025c4ce9cbc664ae6245d042290
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/README.md
@@ -0,0 +1,74 @@
+# FSDP2 Benchmarks
+
+This benchmark showcases `FSDP2` in 🤗 `accelerate` and compares it to `torch` baseline.
+
+## Overview
+
+This benchmark consists of two parts:
+- `main.py` is the main script that runs the benchmark
+- `visualize.py` is the script that visualizes the results (if `--output_dir` was specified for the previous command)
+
+## Motivation
+
+We want to showcase that 🤗 `accelerate`'s integration of `FSDP2` is on par raw PyTorch, and highlight a "broken" part in PyTorch that creating an optimizer before applying `FSDP2` **doesn't result in a working training loop**. (more on this later)
+This script showcases **matching memory usage and convergence between `accelerate` and `torch`'s baseline.**
+To deal with this breaking change (and maintain backward compatibility with FSDP1 in terms of an API), `accelerate` had to come up with a workaround since `accelerate` assumes that the user will nearly always create a model, optimizer, scheduler, etc beforehand and bring them themselves. This lead to an issue of a stark increase in memory as well as the model not even training if the user creates an optimizer beforehand.
+To workaround this, we replace the parameters inside the optimizer with the newly created FSDP2 sharded ones. More about this can be found in this [blog post (TBD)](TODO)
+> [!WARNING]
+> This script is intended to fit on 2x 24GB GPUs, though on so few GPUs it's not possible to see the memory difference (discrepancies in grad allocation result in lower memory usage in the non-fixed case), only the difference in convergence. Below are attached results from 8x H100 GPUs where the difference is visible.
+> TLDR: more GPUs = bigger memory difference between fixed and non-fixed cases.
+
+## Results
+
+Here are the results from running the benchmark on 8x H100 GPUs:
+
+
+
+
+
+
+
+
+As you can see, the memory usage of `accelerate` and `torch_post_shard` (the **intended** way) are very similar, while `torch_pre_shard_not_fixed` uses significantly more memory. Our fix in `torch_pre_shard_fixed` brings the memory usage back in line with the **intended** approach.
+
+> [!WARNING]
+> Timing discrepancies are due to the benchmarks being ran in 1 script.
+
+
+## Running
+
+To run the benchmark, you can either use `accelerate launch` or `torchrun`:
+```bash
+accelerate launch main.py
+```
+```bash
+# For two GPUs
+torchrun --nproc_per_node 2 main.py
+```
+
+This supports multiple configurable options, you can learn about them by running:
+```bash
+python3 main.py --help
+```
+
+This script will run 4 different benchmarks:
+- `torch_optimizer_after_fsdp`: `torch` baseline where optimizer is created after applying `FSDP2`, this is the **intended** way to do it
+- `torch_optimizer_before_fsdp_not_fixed`: `torch` baseline where optimizer is created before applying `FSDP2` without fixing the optimizer parameters
+- `torch_optimizer_before_fsdp_fixed`: `torch` baseline where optimizer is created before applying `FSDP2` with our fix to the optimizer
+- `accelerate`: `accelerate`'s own integration of `FSDP2` where optimizer is created before applying `FSDP2`, but we apply our fix to the optimizer
+
+Memory results are saved in a folder specified by `--output_dir` argument.
+Optionally, you can specify `--save_memory_snapshot` to save the torch memory snapshot, which can then be viewed using [`torch memory viz`](https://pytorch.org/memory_viz)
+
+## Visualizing results
+
+To visualize the results, you can run:
+
+```bash
+python3 visualize.py --dir
+```
+
+This will then create two plots, showcasing allocated and reserved memory usage between all the different benchmarks discussed above.
+
+
+
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/imgs/allocated_memory.png b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/imgs/allocated_memory.png
new file mode 100644
index 0000000000000000000000000000000000000000..4db62fd87b0444eec6a97eb7e48907ee7ab04145
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/imgs/allocated_memory.png
@@ -0,0 +1,3 @@
+version https://git-lfs.github.com/spec/v1
+oid sha256:b59c0613d1fa645724985f9baf03227d88ee9b007423b1932952c874505dae77
+size 127509
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/imgs/reserved_memory.png b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/imgs/reserved_memory.png
new file mode 100644
index 0000000000000000000000000000000000000000..4e98e6d65d8c425de095830f81cbaed42684ac3d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/imgs/reserved_memory.png
@@ -0,0 +1,3 @@
+version https://git-lfs.github.com/spec/v1
+oid sha256:44bf13521013af88979fe220121c774c87e1395663b10d95a471d454708a4624
+size 57655
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/main.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/main.py
new file mode 100644
index 0000000000000000000000000000000000000000..2e2499aa6f60f1ab57d3ea930dddb077b785553a
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/main.py
@@ -0,0 +1,122 @@
+# Copyright 2025 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import functools
+from typing import Callable
+
+import torch
+
+from accelerate import Accelerator
+from utils import parse_args, prepare_accelerate, prepare_torch
+
+
+MODEL_NAME = "Qwen/Qwen2.5-1.5B-Instruct"
+LEARNING_RATE = 3e-5
+
+CONFIG = {
+ "model_name": MODEL_NAME,
+ "learning_rate": LEARNING_RATE,
+}
+
+
+def train(
+ model: torch.nn.Module,
+ optimizer: torch.optim.Optimizer,
+ train_dataloader: torch.utils.data.DataLoader,
+ accelerator: Accelerator,
+) -> torch.Tensor:
+ losses = []
+ for batch in train_dataloader:
+ optimizer.zero_grad()
+ outputs = model(**batch, use_cache=False)
+
+ loss = outputs.loss
+ losses.append(loss.item())
+ accelerator.backward(loss)
+ optimizer.step()
+
+ return torch.tensor(losses)
+
+
+def evaluate(args, config: dict, init_fn: Callable, run_name: str) -> torch.Tensor:
+ model, optimizer, dataloader, accelerator, memory_tracker = init_fn(args, config)
+
+ loss = train(model, optimizer, dataloader, accelerator)
+
+ memory_tracker.stop()
+ msg = f"""Results for {run_name} (rank 0):
+Loss: {loss[-1].item()}
+Peak Allocated Memory: {float(memory_tracker.peak_allocated_memory):.2f} MB
+Peak Reserved Memory: {float(memory_tracker.peak_reserved_memory):.2f} MB
+{"-" * 34}"""
+ accelerator.print(msg)
+ return loss
+
+
+def main():
+ args = parse_args()
+ evaluations = [
+ functools.partial(
+ evaluate,
+ init_fn=functools.partial(prepare_torch, post_shard_optimizer=False, apply_optimizer_fix=True),
+ run_name="Optimizer Before FSDP (w/ fix)",
+ ),
+ functools.partial(
+ evaluate,
+ init_fn=functools.partial(prepare_torch, post_shard_optimizer=False, apply_optimizer_fix=False),
+ run_name="Optimizer Before FSDP (w/o fix)",
+ ),
+ functools.partial(
+ evaluate,
+ init_fn=functools.partial(prepare_torch, post_shard_optimizer=True),
+ run_name="Optimizer After FSDP",
+ ),
+ functools.partial(evaluate, init_fn=prepare_accelerate, run_name="Accelerate"),
+ ]
+ labels = [
+ "Optimizer Before FSDP (w/ fix)",
+ "Optimizer Before FSDP (w/o fix)",
+ "Optimizer After FSDP",
+ "Accelerate",
+ ]
+
+ results = {}
+ torch.use_deterministic_algorithms(True)
+
+ for evaluation, label in zip(evaluations, labels):
+ results[label] = evaluation(args, CONFIG)
+
+ torch.testing.assert_close(
+ results["Optimizer After FSDP"],
+ results["Optimizer Before FSDP (w/ fix)"],
+ msg="Optimizer After FSDP and Optimizer Before FSDP (w/ fix) should be the same",
+ )
+
+ torch.testing.assert_close(
+ results["Optimizer After FSDP"],
+ results["Accelerate"],
+ msg="Optimizer After FSDP and Accelerate should be the same",
+ )
+
+ torch.testing.assert_close(
+ results["Accelerate"],
+ results["Optimizer Before FSDP (w/ fix)"],
+ msg="Accelerate and Optimizer Before FSDP (w/ fix) should be the same",
+ )
+
+ torch.distributed.destroy_process_group()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/measure_utils.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/measure_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..bf73d5da6d6c4d8bb12f69bd5547defcb3ca46f6
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/measure_utils.py
@@ -0,0 +1,130 @@
+# Copyright 2025 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import gc
+import json
+import os
+import threading
+import time
+
+import psutil
+import torch
+
+from accelerate import PartialState
+
+
+class MemoryTracker:
+ def __init__(
+ self,
+ device: torch.device,
+ output_directory: str,
+ run_name: str,
+ save_memory_snapshot: bool,
+ log_interval: float = 0.01,
+ ):
+ """Class for tracking gpu and cpu memory usage of the process.
+
+ Args:
+ device (`torch.device`):
+ PyTorch device to monitor.
+ output_directory (`str`):
+ Directory to save the memory usage data to, will be created if it doesn't exist.
+ run_name (`str`):
+ Name of the run, will be used to name the output files.
+ save_memory_snapshot (`bool`):
+ Whether to also save `torch.cuda.memory._dump_snapshot` to the output directory.
+ log_interval (`float`, *optional*):
+ Interval in seconds between memory measurements. Defaults to 0.01.
+ """
+ self.log_interval = log_interval
+ self.save_memory_snapshot = save_memory_snapshot
+ self.output_directory = output_directory
+ self.run_name = run_name
+
+ self.timestamps = []
+ self.allocated_memory = []
+ self.reserved_memory = []
+ self.virtual_memory = []
+
+ self.start_time = None
+ self.running = False
+
+ self._thread = None
+ self._state = PartialState()
+ self._process = psutil.Process()
+ self._device = device
+ self.torch_accelerator_module = getattr(torch, device.type, torch.cuda)
+
+ def _monitor(self):
+ self.start_time = time.time()
+
+ while self.running:
+ allocated = self.torch_accelerator_module.memory_allocated(self._device) / (1024 * 1024)
+ reserved = self.torch_accelerator_module.memory_reserved(self._device) / (1024 * 1024)
+ virtual_memory = self._process.memory_info().rss / (1024 * 1024)
+
+ self.allocated_memory.append(allocated)
+ self.reserved_memory.append(reserved)
+ self.virtual_memory.append(virtual_memory)
+ self.timestamps.append(time.time() - self.start_time)
+
+ time.sleep(self.log_interval)
+
+ def start(self):
+ gc.collect()
+ self.torch_accelerator_module.empty_cache()
+
+ if self.output_directory:
+ os.makedirs(self.output_directory, exist_ok=True)
+
+ if self.save_memory_snapshot:
+ self.torch_accelerator_module.memory._record_memory_history()
+
+ self.running = True
+ self._thread = threading.Thread(target=self._monitor)
+ self._thread.daemon = True
+ self._thread.start()
+
+ def stop(self):
+ self.running = False
+ if self._thread:
+ self._thread.join()
+
+ if self.save_memory_snapshot and self._state.is_main_process and self.output_directory:
+ output_file = os.path.join(self.output_directory, f"{self.run_name}_memory_snapshot.pkl")
+ self.torch_accelerator_module.memory._dump_snapshot(output_file)
+
+ if self._state.is_main_process and self.output_directory:
+ path = os.path.join(self.output_directory, f"{self.run_name}_memory_usage.json")
+ with open(path, "w") as f:
+ json.dump(
+ {
+ "timestamps": self.timestamps,
+ "allocated_memory": self.allocated_memory,
+ "reserved_memory": self.reserved_memory,
+ "virtual_memory": self.virtual_memory,
+ },
+ f,
+ )
+ if self.save_memory_snapshot:
+ self.torch_accelerator_module.memory._record_memory_history(False)
+ self.torch_accelerator_module.empty_cache()
+
+ @property
+ def peak_allocated_memory(self):
+ return max(self.allocated_memory)
+
+ @property
+ def peak_reserved_memory(self):
+ return max(self.reserved_memory)
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/utils.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..b23fa8cc22aa4e03d0eb8bd505b6f865b8cfde80
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/utils.py
@@ -0,0 +1,290 @@
+# Copyright 2025 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import argparse
+from types import MethodType
+from typing import Union
+
+import torch
+from datasets import load_dataset
+from measure_utils import MemoryTracker
+from torch.distributed.fsdp import MixedPrecisionPolicy, fully_shard
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoConfig, AutoModelForCausalLM, AutoTokenizer, DataCollatorForLanguageModeling
+from transformers.models.qwen2.modeling_qwen2 import Qwen2DecoderLayer
+
+from accelerate import Accelerator, FullyShardedDataParallelPlugin
+from accelerate.state import AcceleratorState, is_initialized
+from accelerate.utils import convert_outputs_to_fp32, set_seed
+
+
+SEED = 421
+
+
+def get_named_parameters(model: torch.nn.Module, drop_refs: bool = False) -> dict[str, Union[torch.Tensor, int]]:
+ """
+ This function returns a dictionary mapping the parameter names to their data pointers or
+ the original parameters if `drop_refs` is `False`.
+ It is used to get the original parameter names before `fully_shard` is applied.
+
+ We only return the data pointers, so we drop the references to the original parameters
+ and `fully_shard` will then trigger a new allocation for the sharded ones.
+
+ Args:
+ model (`torch.nn.Module`): Model instance to get the named parameters from
+ drop_refs (`bool`, *optional*, defaults to `False`): Whether to drop the references to the original parameters
+
+ Returns:
+ `dict[str, Union[torch.Tensor, int]]`: Dictionary mapping the parameter names to their data pointers or the original parameters if `drop_refs` is `False`
+ """
+ named_parameters = {}
+ for n, p in model.named_parameters():
+ # We only preserve the data pointers to have the unique 1:1 mapping between the original and the sharded parameters
+ named_parameters[n] = p.data_ptr() if drop_refs else p
+ return named_parameters
+
+
+def replace_optimizer_params(optimizer: torch.optim.Optimizer):
+ """
+ This function is called before using `fully_shard` on the model. It replaces the parameters of the optimizer with
+ empty tensors, so `fully_shard` can trigger a new allocation for the sharded ones. After this, we swap the parameters
+ `data_ptr` to the original one, so we can reuse that later to map the sharded parameters to the original ones.
+ This function modifies the optimizer in-place.
+
+ Args:
+ optimizer (torch.optim.Optimizer): Optimizer instance which contains the original model parameters
+ """
+
+ for param_group in optimizer.param_groups:
+ for i, p in enumerate(param_group["params"]):
+ # We drop a reference to the original param here, so that _move_states_to_device triggers a reallocation
+ # This is required or else the `fully_shard` -> `_move_states_to_device` uses the original memory address
+ # for the sharded parameters, and we get a weird/undefined behavior.
+ param_group["params"][i] = torch.empty_like(p)
+
+ # We save the original data_ptr, so we can swap back the parameters later
+ param_group["params"][i].data_ptr = p.data_ptr()
+
+
+def swap_back_optimizer_params(
+ model: torch.nn.Module, optimizer: torch.optim.Optimizer, old_named_parameter_pointers: dict[str, int]
+):
+ """
+ This function is the counterpart of `replace_optimizer_params`. It is called after `fully_shard` being applied to
+ the model. It swaps the parameters of the optimizer to their sharded counterparts.
+ It is done using the `data_ptr` mapping prepared in `replace_optimizer_params` and `get_named_parameters`.
+
+ Args:
+ model (`torch.nn.Module`): Model instance to get the new named parameters from
+ optimizer (`torch.optim.Optimizer`): Optimizer instance to swap the parameters of
+ old_named_parameter_pointers (`dict[str, int]`): Dictionary mapping the original parameter names: data_ptrs to the new ones
+ """
+ # We get the new named parameters after `fully_shard` being applied
+ # We don't drop the references as we need the sharded parameters now
+ new_named_parameters = get_named_parameters(model, drop_refs=False)
+
+ # We create a mapping from the original data_ptr to the new sharded param corresponding to it
+ mapping = {p: new_named_parameters[n] for n, p in old_named_parameter_pointers.items()}
+
+ for param_group in optimizer.param_groups:
+ # We swap the parameters of the optimizer to the new sharded ones
+ param_group["params"] = [mapping[p.data_ptr] for p in param_group["params"]]
+
+
+def parse_args():
+ parser = argparse.ArgumentParser()
+ parser.add_argument(
+ "--output_dir",
+ type=str,
+ help="Directory to save the benchmarking results.",
+ )
+ parser.add_argument(
+ "--save_memory_snapshot",
+ action="store_true",
+ default=False,
+ help="If True, `torch.cuda.memory._dump_snapshot` will be used to additionaly save the memory trace.",
+ )
+ ######################
+ # Training arguments #
+ ######################
+ parser.add_argument(
+ "--batch_size",
+ type=int,
+ default=2,
+ help="Batch size for the training loop.",
+ )
+ parser.add_argument(
+ "--block_size",
+ type=int,
+ default=128,
+ help="The maximum sequence length to use with the model.",
+ )
+ parser.add_argument(
+ "--dataset_fraction",
+ type=float,
+ default=1.0,
+ help="Fraction of the dataset to use.",
+ )
+ return parser.parse_args()
+
+
+def prepare_dataloader(tokenizer, args, accelerator: Accelerator) -> DataLoader:
+ dataset = load_dataset("tiny_shakespeare", split="train", trust_remote_code=True)
+
+ def tokenize_function(example):
+ return tokenizer(
+ example["text"],
+ )
+
+ dataset = dataset.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["text"],
+ )
+
+ block_size = min(tokenizer.model_max_length, args.block_size)
+
+ def group_texts(examples):
+ concatenated_examples = {k: sum(examples[k], []) for k in examples.keys()}
+ total_length = len(concatenated_examples[list(examples.keys())[0]])
+
+ total_length = (total_length // block_size) * block_size
+
+ result = {
+ k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
+ for k, t in concatenated_examples.items()
+ }
+
+ result["labels"] = result["input_ids"].copy()
+ return result
+
+ dataset = dataset.map(group_texts, batched=True)
+ dataset = dataset.select(range(int(len(dataset) * args.dataset_fraction)))
+
+ def collate_fn(examples):
+ return DataCollatorForLanguageModeling(
+ tokenizer=tokenizer,
+ mlm=False,
+ )(examples)
+
+ dataloader = DataLoader(
+ dataset,
+ batch_size=args.batch_size,
+ collate_fn=collate_fn,
+ )
+ dataloader = accelerator.prepare(dataloader)
+ return dataloader
+
+
+def get_model(model_name: str):
+ # We reguire model to be loaded in fp32, otherwise benchmarks don't match as accelerate does upcasting of parameters to fp32
+ config = AutoConfig.from_pretrained(model_name, trust_remote_code=True, torch_dtype=torch.float32)
+ model = AutoModelForCausalLM.from_config(config)
+ return model
+
+
+def get_tokenizer(model_name: str):
+ tokenizer = AutoTokenizer.from_pretrained(model_name, trust_remote_code=True)
+ tokenizer.pad_token = tokenizer.eos_token
+ return tokenizer
+
+
+def prepare_torch(
+ args, config: dict, post_shard_optimizer: bool = False, apply_optimizer_fix: bool = False
+) -> tuple[torch.nn.Module, torch.optim.Optimizer, torch.utils.data.DataLoader, Accelerator]:
+ mp_policy = MixedPrecisionPolicy(
+ param_dtype=torch.bfloat16,
+ reduce_dtype=torch.bfloat16,
+ output_dtype=torch.bfloat16,
+ )
+
+ accelerator = Accelerator(mixed_precision="bf16")
+ set_seed(SEED)
+ is_fixed = "fixed" if apply_optimizer_fix else "not_fixed"
+ is_post_shard = "optimizer_after_fsdp" if post_shard_optimizer else "optimizer_before_fsdp"
+ run_name = f"torch_{is_post_shard}" if post_shard_optimizer else f"torch_{is_post_shard}_{is_fixed}"
+
+ tokenizer = get_tokenizer(config["model_name"])
+ train_dataloader = prepare_dataloader(tokenizer, args, accelerator)
+
+ memory_tracker = MemoryTracker(accelerator.device, args.output_dir, run_name, args.save_memory_snapshot)
+ memory_tracker.start()
+
+ model = get_model(config["model_name"])
+ optimizer = None
+
+ if not post_shard_optimizer:
+ optimizer = AdamW(model.parameters(), lr=config["learning_rate"])
+
+ if apply_optimizer_fix:
+ # We drop the references to the original parameters, so that `fully_shard` can trigger a new allocation
+ # Then we get the `module_name: data_ptr` mapping, so we can swap back the parameters later
+ old_named_parameters = get_named_parameters(model, drop_refs=True)
+
+ # We replace the parameters of the optimizer with empty tensors, so that `fully_shard` can trigger a new allocation
+ # We also change the `data_ptr` of the parameters to the original ones, so we can swap back the parameters later
+ replace_optimizer_params(optimizer)
+
+ for module in model.modules():
+ if isinstance(module, Qwen2DecoderLayer):
+ fully_shard(module, mp_policy=mp_policy)
+ fully_shard(model, mp_policy=mp_policy)
+
+ # We do this to imitate how accelerate forces outputs to be in fp32 via `convert_outputs_to_fp32`
+ autocast_context = torch.autocast(device_type=accelerator.state.device.type, dtype=torch.bfloat16)
+ model_forward_func = model.forward.__func__
+ new_forward = autocast_context(model_forward_func)
+ model.forward = MethodType(new_forward, model)
+ model.forward = MethodType(convert_outputs_to_fp32(model.forward.__func__), model)
+
+ if post_shard_optimizer:
+ optimizer = AdamW(model.parameters(), lr=config["learning_rate"])
+
+ if not post_shard_optimizer and apply_optimizer_fix:
+ # We swap back the parameters of the optimizer to the original ones
+ swap_back_optimizer_params(model, optimizer, old_named_parameters)
+
+ return model, optimizer, train_dataloader, accelerator, memory_tracker
+
+
+def prepare_accelerate(
+ args, config: dict
+) -> tuple[torch.nn.Module, torch.optim.Optimizer, torch.utils.data.DataLoader, Accelerator]:
+ if is_initialized():
+ AcceleratorState()._reset_state(True)
+
+ fsdp_plugin = FullyShardedDataParallelPlugin(
+ fsdp_version=2,
+ auto_wrap_policy="transformer_based_wrap",
+ transformer_cls_names_to_wrap=["Qwen2DecoderLayer"],
+ )
+ accelerator = Accelerator(
+ fsdp_plugin=fsdp_plugin,
+ mixed_precision="bf16",
+ )
+ set_seed(SEED)
+
+ tokenizer = get_tokenizer(config["model_name"])
+ train_dataloader = prepare_dataloader(tokenizer, args, accelerator)
+
+ memory_tracker = MemoryTracker(accelerator.device, args.output_dir, "accelerate", args.save_memory_snapshot)
+ memory_tracker.start()
+
+ model = get_model(config["model_name"])
+ optimizer = AdamW(model.parameters(), lr=config["learning_rate"])
+
+ model, optimizer = accelerator.prepare(model, optimizer)
+
+ return model, optimizer, train_dataloader, accelerator, memory_tracker
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/visualize.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/visualize.py
new file mode 100644
index 0000000000000000000000000000000000000000..6c4bdf4a2e68a3708262155a9e0718cd894d0be2
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/fsdp2/visualize.py
@@ -0,0 +1,114 @@
+# Copyright 2025 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import argparse
+import json
+
+import matplotlib.pyplot as plt
+
+
+def parse_args():
+ parser = argparse.ArgumentParser()
+ parser.add_argument("--dir", type=str, help="Directory containing the memory usage data")
+ parser.add_argument(
+ "--memory_threshold",
+ type=int,
+ default=0,
+ help="Memory threshold to filter data that is below this value (only filters 1st `--filter_partition` of the points which should roughtly correspond to the model loading)",
+ )
+ parser.add_argument(
+ "--filter_partition",
+ type=float,
+ default=1 / 3,
+ help="Partition to drop data from that are below the memory threshold",
+ )
+ return parser.parse_args()
+
+
+def filter_data(data, memory_threshold, filter_partition, key):
+ timestamps = data["timestamps"]
+ memory = data[key]
+
+ mid_point = int(len(timestamps) * filter_partition)
+ filtered_times = []
+ filtered_memory = []
+ for i, (t, m) in enumerate(zip(timestamps, memory)):
+ if i < mid_point and m < memory_threshold:
+ continue
+ filtered_times.append(t)
+ filtered_memory.append(m)
+ return filtered_times, filtered_memory
+
+
+def compare_memory_usage(data, labels, memory_threshold, filter_partition):
+ plt.style.use("seaborn-v0_8")
+ colors = ["#2ecc71", "#e74c3c", "#3498db", "#f1c40f"]
+
+ fig1, ax1 = plt.subplots(figsize=(15, 5))
+ for data_item, label, color in zip(data, labels, colors):
+ timestamps, allocated = filter_data(data_item, memory_threshold, filter_partition, "allocated_memory")
+ ax1.plot(timestamps, allocated, label=label, color=color, linewidth=2)
+
+ ax1.set_xlabel("Time (s)", fontsize=12)
+ ax1.set_ylabel("Allocated Memory (GB)", fontsize=12)
+ ax1.set_title("Allocated Memory Usage Over Time", fontsize=14, pad=15)
+ ax1.grid(True, linestyle="--", alpha=0.7)
+ ax1.legend(frameon=True, fancybox=True, shadow=True, fontsize=10)
+ ax1.spines["top"].set_visible(False)
+ ax1.spines["right"].set_visible(False)
+ plt.tight_layout()
+
+ fig2, ax2 = plt.subplots(figsize=(15, 5))
+ for data_item, label, color in zip(data, labels, colors):
+ timestamps, reserved = filter_data(data_item, memory_threshold, filter_partition, "reserved_memory")
+ ax2.plot(timestamps, reserved, label=label, color=color, linewidth=2)
+
+ ax2.set_xlabel("Time (s)", fontsize=12)
+ ax2.set_ylabel("Reserved Memory (GB)", fontsize=12)
+ ax2.set_title("Reserved Memory Usage Over Time", fontsize=14, pad=15)
+ ax2.grid(True, linestyle="--", alpha=0.7)
+ ax2.legend(frameon=True, fancybox=True, shadow=True, fontsize=10)
+ ax2.spines["top"].set_visible(False)
+ ax2.spines["right"].set_visible(False)
+ plt.tight_layout()
+
+ return fig1, fig2
+
+
+if __name__ == "__main__":
+ args = parse_args()
+ DIR = args.dir
+ with open(f"{DIR}/torch_optimizer_before_fsdp_not_fixed_memory_usage.json") as f:
+ optimizer_before_fsdp_not_fixed = json.load(f)
+
+ with open(f"{DIR}/torch_optimizer_after_fsdp_memory_usage.json") as f:
+ optimizer_after_fsdp = json.load(f)
+
+ with open(f"{DIR}/torch_optimizer_before_fsdp_fixed_memory_usage.json") as f:
+ optimizer_before_fsdp_fixed = json.load(f)
+
+ with open(f"{DIR}/accelerate_memory_usage.json") as f:
+ accelerate = json.load(f)
+
+ data = [optimizer_before_fsdp_not_fixed, optimizer_before_fsdp_fixed, optimizer_after_fsdp, accelerate]
+ labels = [
+ "Optimizer Before FSDP (w/o fix)",
+ "Optimizer Before FSDP (w/ fix)",
+ "Optimizer After FSDP",
+ "Accelerate",
+ ]
+
+ fig1, fig2 = compare_memory_usage(data, labels, args.memory_threshold, args.filter_partition)
+ fig1.savefig(f"{DIR}/allocated_memory.png")
+ fig2.savefig(f"{DIR}/reserved_memory.png")
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/torch.compile/README.md b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/torch.compile/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..8e70193f341dddd940d05dab613fb6f987d5338d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/torch.compile/README.md
@@ -0,0 +1,111 @@
+# Regional Compilation Benchmark
+
+This benchmark compares different compilation strategies using PyTorch's `torch.compile` and Accelerate's `compile_regions` utility, which is based on the recipe in [PyTorch documentation](https://pytorch.org/tutorials/recipes/regional_compilation.html).
+
+## Overview
+
+The benchmark evaluates three approaches:
+
+- **Baseline**: No compilation, standard PyTorch eager execution.
+- **Full compilation**: Using PyTorch's `torch.compile()` on the entire model.
+- **Regional compilation**: Using `accelerate.utils.compile_regions()` which targets specific blocks of the model to optimize compilation time.
+
+Each approach is tested with different batch sizes (1 and 4) and sequence lengths (128) on various LLaMA-based models ranging from 1B to 13B parameters. We purposefully run the forward pass outside of the `torch.no_grad()` context to simulate performance in a training environment, where gradients are needed.
+
+## Usage
+
+To run this benchmark:
+
+```bash
+python regional_compilation.py
+```
+
+The script will automatically download the model configurations, create models, and benchmark both compilation and inference times across different scenarios.
+
+## Requirements
+
+- Suitable GPU memory for the models being tested.
+- PyTorch with CUDA support.
+- Transformers library.
+- Accelerate library.
+
+## Results
+
+The benchmark results are summarized in the following figures:
+
+- Compilation time is how long it takes to run the first forward pass.
+- Speedup factor is the ratio of non-compiled baseline inference time to the fully/regionally compiled inference time.
+
+
+
+
+
+
+
+
+Full results are available in the tables below:
+
+```markdown
+[-------------------------------------------------- NousResearch/Llama-3.2-1B ---------------------------------------------------]
+ | Inference time (1x128) | Inference time (4x128) | Compile time (1x128) | Compile time (4x128)
+1 threads: -----------------------------------------------------------------------------------------------------------------------
+ Baseline | 18.3 | 18.4 | |
+ Full compilation | 6.3 | 10.0 | 10696.4 | 10248.0
+ Regional compilation | 9.7 | 10.0 | 1952.7 | 2903.9
+
+Times are in milliseconds (ms).
+
+[---------------------------------------------- NousResearch/Hermes-3-Llama-3.2-3B ----------------------------------------------]
+ | Inference time (1x128) | Inference time (4x128) | Compile time (1x128) | Compile time (4x128)
+1 threads: -----------------------------------------------------------------------------------------------------------------------
+ Baseline | 33.4 | 33.6 | |
+ Full compilation | 11.2 | 23.9 | 17857.5 | 17736.5
+ Regional compilation | 17.3 | 23.7 | 2993.2 | 2478.8
+
+Times are in milliseconds (ms).
+
+[---------------------------------------------- NousResearch/Hermes-3-Llama-3.1-8B ----------------------------------------------]
+ | Inference time (1x128) | Inference time (4x128) | Compile time (1x128) | Compile time (4x128)
+1 threads: -----------------------------------------------------------------------------------------------------------------------
+ Baseline | 40.3 | 59.5 | |
+ Full compilation | 18.9 | 54.4 | 20437.8 | 20152.3
+ Regional compilation | 19.7 | 54.0 | 2903.1 | 2438.0
+
+Times are in milliseconds (ms).
+
+[--------------------------------------------- NousResearch/Nous-Hermes-Llama2-13b ----------------------------------------------]
+ | Inference time (1x128) | Inference time (4x128) | Compile time (1x128) | Compile time (4x128)
+1 threads: -----------------------------------------------------------------------------------------------------------------------
+ Baseline | 45.5 | 100.4 | |
+ Full compilation | 29.4 | 89.7 | 23099.4 | 22885.9
+ Regional compilation | 29.4 | 87.5 | 2945.5 | 2526.2
+
+Times are in milliseconds (ms).
+```
+
+## Results Summary
+
+### Compilation Time
+
+Regional compilation provides significantly faster compilation times compared to full model compilation:
+
+- **Full compilation**: Takes ~10-23 seconds depending on model size.
+- **Regional compilation**: Takes only ~2-3 seconds across all model sizes.
+- **Speed improvement**: Regional compilation is **5-9x faster** to compile.
+
+### Inference Time
+
+Regional compilation delivers inference performance close to full compilation:
+
+- For batch size 1:
+ - For smaller models (1B-3B): Full compilation has a slight edge over regional compilation.
+ - For larger models (8B-13B): Regional compilation performs similarly to full compilation.
+- For batch size 4: Regional compilation performs similarly to full compilation across all models.
+
+## Key Takeaways
+
+1. **Comparable Performance**: Regional compilation delivers performance speedups similar to full compilation, especially for larger models.
+2. **Faster Compilation**: Regional compilation significantly reduces the time taken to compile models, making it a more efficient choice for deployment.
+3. **Batch Size Impact**: At batch size 4, full compilation and regional compilation perform nearly identically.
+4. **Model Size Impact**: Even with a small batch size, full compilation and regional compilation perform similarly for larger models (8B-13B).
+5. **Practical Application**: For real-world applications, regional compilation is a practical choice for optimizing training cold start times, especially when working with large models.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/torch.compile/imgs/compilation_time.png b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/torch.compile/imgs/compilation_time.png
new file mode 100644
index 0000000000000000000000000000000000000000..e129c7e5495a4f206f20f31078b3b8f468e44b3c
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/torch.compile/imgs/compilation_time.png
@@ -0,0 +1,3 @@
+version https://git-lfs.github.com/spec/v1
+oid sha256:10f7424e7eda20608d628b469ee51f3d42e987499746237f9a423d3996f84a62
+size 248194
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/torch.compile/imgs/speedup_factor.png b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/torch.compile/imgs/speedup_factor.png
new file mode 100644
index 0000000000000000000000000000000000000000..cb71e32c214f6f4391d05d2be2ded297d5a4c0d0
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/torch.compile/imgs/speedup_factor.png
@@ -0,0 +1,3 @@
+version https://git-lfs.github.com/spec/v1
+oid sha256:18d22ad19523e455875e797d8fa4370404b8d95099f5b1366f7498adead17155
+size 222905
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/torch.compile/regional_compilation.py b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/torch.compile/regional_compilation.py
new file mode 100644
index 0000000000000000000000000000000000000000..6619cbc6d0ae4e14e764edc2a8f54b94c81a050f
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/benchmarks/torch.compile/regional_compilation.py
@@ -0,0 +1,77 @@
+# Copyright 2025 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import torch
+from torch.utils.benchmark import Compare, Timer
+from transformers import AutoConfig, AutoModelForCausalLM
+
+from accelerate.test_utils.testing import get_backend
+from accelerate.utils import compile_regions
+
+
+torch.set_float32_matmul_precision("high")
+
+COMPILE_ITERS = 2
+INFERENCE_ITERS = 100
+
+BASELINE = "Baseline"
+COMPILE_TIME = "Compile time"
+INFRENCE_TIME = "Inference time"
+FULL_COMPILATION = "Full compilation"
+REGIONAL_COMPILATION = "Regional compilation"
+
+INFRENCE_STMT = "model(input_ids, use_cache=False)"
+COMPILE_STMT = f"torch._dynamo.reset(); torch._inductor.utils.clear_inductor_caches(); {INFRENCE_STMT}"
+
+torch_device_type, _, _ = get_backend()
+
+results = []
+for model_id in [
+ # non-gated llama models
+ "NousResearch/Llama-3.2-1B",
+ "NousResearch/Hermes-3-Llama-3.2-3B",
+ "NousResearch/Hermes-3-Llama-3.1-8B",
+ "NousResearch/Nous-Hermes-Llama2-13b",
+]:
+ with torch.device(torch_device_type):
+ config = AutoConfig.from_pretrained(model_id)
+ model = AutoModelForCausalLM.from_config(config).to(dtype=torch.float16).eval()
+
+ full_compilation_model = torch.compile(model)
+ regional_compilation_model = compile_regions(model)
+
+ for model, sub_label, description, stmt, iters in [
+ (model, BASELINE, INFRENCE_TIME, INFRENCE_STMT, INFERENCE_ITERS),
+ (full_compilation_model, FULL_COMPILATION, COMPILE_TIME, COMPILE_STMT, COMPILE_ITERS),
+ (full_compilation_model, FULL_COMPILATION, INFRENCE_TIME, INFRENCE_STMT, INFERENCE_ITERS),
+ (regional_compilation_model, REGIONAL_COMPILATION, COMPILE_TIME, COMPILE_STMT, COMPILE_ITERS),
+ (regional_compilation_model, REGIONAL_COMPILATION, INFRENCE_TIME, INFRENCE_STMT, INFERENCE_ITERS),
+ ]:
+ for batch_size, sequence_length in [(1, 128), (4, 128)]:
+ input_ids = torch.randint(
+ 0, 1000, size=(batch_size, sequence_length), dtype=torch.int64, device=torch_device_type
+ )
+ results.append(
+ Timer(
+ label=model_id,
+ sub_label=sub_label,
+ description=f"{description} ({batch_size}x{sequence_length})",
+ globals={"model": model, "input_ids": input_ids},
+ stmt=stmt,
+ ).timeit(number=iters)
+ )
+
+compare = Compare(results)
+compare.colorize()
+compare.print()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docker/README.md b/tasks/tasksmith-3d762a2acfee/tests/source/docker/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..2e19e6caa4ae26b61dec7602f02199d3a4daf036
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docker/README.md
@@ -0,0 +1,74 @@
+
+
+# Official Hugging Face Accelerate Docker Images
+
+Accelerate publishes a variety of docker versions as part of our CI that users can also use. These are stable images that Accelerate can run off of which comes with a variety of different setup configurations, all of which are officially hosted on [Docker Hub](https://hub.docker.com/r/huggingface/accelerate).
+
+A breakdown of each are given below
+
+## Naming Conventions
+
+Accelerate docker images follow a tagging convention of:
+
+```bash
+huggingface/accelerate:{accelerator}-{nightly,release}
+```
+
+`accelerator` in this instance is one of many applical pre-configured backend supports:
+* `gpu`: Comes compiled off of the `nvidia/cuda` image and includes core parts like `bitsandbytes`. Runs off python 3.9.
+* `cpu`: Comes compiled off of `python:3.9-slim` and is designed for non-CUDA based workloads.
+* More to come soon
+* `gpu-deepspeed`: Comes compiled off of the `nvidia/cuda` image and includes core parts like `bitsandbytes` as well as the latest `deepspeed` version. Runs off python 3.10.
+* `gpu-fp8-transformerengine`: Comes compiled off of `nvcr.io/nvidia/pytorch` and is specifically for running the `benchmarks/fp8` scripts on devices which support FP8 operations using the `TransformerEngine` library (RTX 4090, H100, etc)
+
+## Nightlies vs Releases
+
+Each release a new build is pushed with a version number included in the name. For a GPU-supported image of version 0.28.0 for instance, it would look like the following:
+
+```bash
+huggingface/accelerate:gpu-release-0.28.0
+```
+
+Nightlies contain two different image tags. There is a general `nightly` tag which is built each night, and a `nightly-YYYY-MM-DD` which corresponds to a build from a particular date.
+
+For instance, here is an example nightly CPU image from 3/14/2024
+
+```bash
+huggingface/accelerate:cpu-nightly-2024-03-14
+```
+
+## Running the images
+
+Each image comes compiled with `conda` and an `accelerate` environment contains all of the installed dependencies.
+
+To pull down the latest nightly run:
+
+```bash
+docker pull huggingface/accelerate:gpu-nightly
+```
+
+To then run it in interactive mode with GPU-memory available, run:
+
+```bash
+docker container run --gpus all -it huggingface/accelerate:gpu-nightly
+```
+
+## DEPRECATED IMAGES
+
+CPU and GPU docker images were hosted at `huggingface/accelerate-gpu` and `huggingface/accelerate-cpu`. These builds are now outdated and will not receive updates.
+
+The builds at the corresponding `huggingface/accelerate:{gpu,cpu}` contain the same `Dockerfile`, so it's as simple as changing the docker image to the desired ones from above. We will not be deleting these images for posterity, but they will not be receiving updates going forward.
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docker/accelerate-cpu/Dockerfile b/tasks/tasksmith-3d762a2acfee/tests/source/docker/accelerate-cpu/Dockerfile
new file mode 100644
index 0000000000000000000000000000000000000000..cb184a88dab89e28261cffe76a382a950dc9129e
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docker/accelerate-cpu/Dockerfile
@@ -0,0 +1,35 @@
+# Builds CPU-only Docker image of PyTorch
+# Uses multi-staged approach to reduce size
+# Stage 1
+FROM python:3.10-slim as compile-image
+
+ARG DEBIAN_FRONTEND=noninteractive
+
+RUN apt update
+RUN apt-get install -y --no-install-recommends \
+ build-essential \
+ git \
+ gcc
+
+# Setup virtual environment for Docker
+ENV VIRTUAL_ENV=/opt/venv
+RUN python3 -m venv ${VIRTUAL_ENV}
+# Make sure we use the virtualenv
+ENV PATH="${VIRTUAL_ENV}/bin:$PATH"
+WORKDIR /workspace
+# Install specific CPU torch wheel to save on space
+RUN python3 -m pip install --upgrade --no-cache-dir pip
+RUN python3 -m pip install --no-cache-dir \
+ jupyter \
+ git+https://github.com/huggingface/accelerate#egg=accelerate[testing,test_trackers] \
+ --extra-index-url https://download.pytorch.org/whl/cpu
+
+# Stage 2
+FROM python:3.10-slim AS build-image
+COPY --from=compile-image /opt/venv /opt/venv
+RUN useradd -ms /bin/bash user
+USER user
+
+# Make sure we use the virtualenv
+ENV PATH="/opt/venv/bin:$PATH"
+CMD ["/bin/bash"]
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docker/accelerate-gpu-deepspeed/Dockerfile b/tasks/tasksmith-3d762a2acfee/tests/source/docker/accelerate-gpu-deepspeed/Dockerfile
new file mode 100644
index 0000000000000000000000000000000000000000..0c8b965135072b708679480a496c342f2bcdea6d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docker/accelerate-gpu-deepspeed/Dockerfile
@@ -0,0 +1,45 @@
+# Builds GPU docker image of PyTorch specifically
+# Uses multi-staged approach to reduce size
+# Stage 1
+# Use base conda image to reduce time
+FROM continuumio/miniconda3:latest AS compile-image
+# Specify py version
+ENV PYTHON_VERSION=3.10
+# Install apt libs
+RUN apt-get update && \
+ apt-get install -y curl git wget && \
+ apt-get clean && \
+ rm -rf /var/lib/apt/lists*
+
+# Create our conda env
+RUN conda create --name accelerate python=${PYTHON_VERSION} ipython jupyter pip
+# We don't install pytorch here yet since CUDA isn't available
+# instead we use the direct torch wheel
+ENV PATH /opt/conda/envs/accelerate/bin:$PATH
+# Activate our bash shell
+RUN chsh -s /bin/bash
+SHELL ["/bin/bash", "-c"]
+# Activate the conda env, install mpy4pi, and install torch + accelerate
+RUN source activate accelerate && conda install -c conda-forge mpi4py
+RUN source activate accelerate && \
+ python3 -m pip install --no-cache-dir \
+ git+https://github.com/huggingface/accelerate#egg=accelerate[testing,test_trackers,deepspeed] \
+ --extra-index-url https://download.pytorch.org/whl/cu126
+
+RUN python3 -m pip install --no-cache-dir bitsandbytes
+
+# Stage 2
+FROM nvidia/cuda:12.6.3-cudnn-devel-ubuntu22.04 AS build-image
+COPY --from=compile-image /opt/conda /opt/conda
+ENV PATH /opt/conda/bin:$PATH
+
+# Install apt libs
+RUN apt-get update && \
+ apt-get install -y curl git wget && \
+ apt-get clean && \
+ rm -rf /var/lib/apt/lists*
+
+RUN echo "source activate accelerate" >> ~/.profile
+
+# Activate the virtualenv
+CMD ["/bin/bash"]
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docker/accelerate-gpu/Dockerfile b/tasks/tasksmith-3d762a2acfee/tests/source/docker/accelerate-gpu/Dockerfile
new file mode 100644
index 0000000000000000000000000000000000000000..2d6d9639a1bbf9fa4b1187c29794e9ef7b8c4526
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docker/accelerate-gpu/Dockerfile
@@ -0,0 +1,45 @@
+# Builds GPU docker image of PyTorch specifically
+# Uses multi-staged approach to reduce size
+# Stage 1
+# Use base conda image to reduce time
+FROM continuumio/miniconda3:latest AS compile-image
+# Specify py version
+ENV PYTHON_VERSION=3.10
+# Install apt libs
+RUN apt-get update && \
+ apt-get install -y curl git wget && \
+ apt-get clean && \
+ rm -rf /var/lib/apt/lists*
+
+# Create our conda env
+RUN conda create --name accelerate python=${PYTHON_VERSION} ipython jupyter pip
+# We don't install pytorch here yet since CUDA isn't available
+# instead we use the direct torch wheel
+ENV PATH /opt/conda/envs/accelerate/bin:$PATH
+# Activate our bash shell
+RUN chsh -s /bin/bash
+SHELL ["/bin/bash", "-c"]
+# Activate the conda env, install mpy4pi, and install torch + accelerate
+RUN source activate accelerate && conda install -c conda-forge mpi4py
+RUN source activate accelerate && \
+ python3 -m pip install --no-cache-dir \
+ git+https://github.com/huggingface/accelerate#egg=accelerate[testing,test_trackers] \
+ --extra-index-url https://download.pytorch.org/whl/cu126
+
+RUN python3 -m pip install --no-cache-dir bitsandbytes
+
+# Stage 2
+FROM nvidia/cuda:12.6.3-cudnn-devel-ubuntu22.04 AS build-image
+COPY --from=compile-image /opt/conda /opt/conda
+ENV PATH /opt/conda/bin:$PATH
+
+# Install apt libs
+RUN apt-get update && \
+ apt-get install -y curl git wget && \
+ apt-get clean && \
+ rm -rf /var/lib/apt/lists*
+
+RUN echo "source activate accelerate" >> ~/.profile
+
+# Activate the virtualenv
+CMD ["/bin/bash"]
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/Makefile b/tasks/tasksmith-3d762a2acfee/tests/source/docs/Makefile
new file mode 100644
index 0000000000000000000000000000000000000000..8879933e6cda150267451c9e7d07dd22b7b0d3f1
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/Makefile
@@ -0,0 +1,19 @@
+# Minimal makefile for Sphinx documentation
+#
+
+# You can set these variables from the command line.
+SPHINXOPTS =
+SPHINXBUILD = sphinx-build
+SOURCEDIR = source
+BUILDDIR = _build
+
+# Put it first so that "make" without argument is like "make help".
+help:
+ @$(SPHINXBUILD) -M help "$(SOURCEDIR)" "$(BUILDDIR)" $(SPHINXOPTS) $(O)
+
+.PHONY: help Makefile
+
+# Catch-all target: route all unknown targets to Sphinx using the new
+# "make mode" option. $(O) is meant as a shortcut for $(SPHINXOPTS).
+%: Makefile
+ @$(SPHINXBUILD) -M $@ "$(SOURCEDIR)" "$(BUILDDIR)" $(SPHINXOPTS) $(O)
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/README.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..4c089297dfc6f0ae4cf6022d17b4694b81db288a
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/README.md
@@ -0,0 +1,267 @@
+
+
+# Generating the documentation
+
+To generate the documentation, you first have to build it. Several packages are necessary to build the doc,
+you can install them with the following command, at the root of the code repository:
+
+```bash
+pip install -e ".[docs]"
+```
+
+Then you need to install our special tool that builds the documentation:
+
+```bash
+pip install git+https://github.com/huggingface/doc-builder
+```
+
+---
+**NOTE**
+
+You only need to generate the documentation to inspect it locally (if you're planning changes and want to
+check how they look before committing for instance). You don't have to commit the built documentation.
+
+---
+
+## Building the documentation
+
+Once you have setup the `doc-builder` and additional packages, you can generate the documentation by
+typing the following command:
+
+```bash
+doc-builder build accelerate docs/source/ --build_dir ~/tmp/test-build
+```
+
+You can adapt the `--build_dir` to set any temporary folder that you prefer. This command will create it and generate
+the MDX files that will be rendered as the documentation on the main website. You can inspect them in your favorite
+Markdown editor.
+
+## Previewing the documentation
+
+To preview the docs, first install the `watchdog` module with:
+
+```bash
+pip install watchdog
+```
+
+Then run the following command:
+
+```bash
+doc-builder preview {package_name} {path_to_docs}
+```
+
+For example:
+
+```bash
+doc-builder preview accelerate docs/source/
+```
+
+The docs will be viewable at [http://localhost:3000](http://localhost:3000). You can also preview the docs once you have opened a PR. You will see a bot add a comment to a link where the documentation with your changes lives.
+
+---
+**NOTE**
+
+The `preview` command only works with existing doc files. When you add a completely new file, you need to update `_toctree.yml` & restart `preview` command (`ctrl-c` to stop it & call `doc-builder preview ...` again).
+
+---
+
+## Adding a new element to the navigation bar
+
+Accepted files are Markdown (.md).
+
+Create a file with its extension and put it in the source directory. You can then link it to the toc-tree by putting
+the filename without the extension in the [`_toctree.yml`](https://github.com/huggingface/accelerate/blob/main/docs/source/_toctree.yml) file.
+
+## Renaming section headers and moving sections
+
+It helps to keep the old links working when renaming the section header and/or moving sections from one document to another. This is because the old links are likely to be used in Issues, Forums, and Social media and it'd make for a much more superior user experience if users reading those months later could still easily navigate to the originally intended information.
+
+Therefore, we simply keep a little map of moved sections at the end of the document where the original section was. The key is to preserve the original anchor.
+
+So if you renamed a section from: "Section A" to "Section B", then you can add at the end of the file:
+
+```
+Sections that were moved:
+
+[ Section A ]
+```
+and of course, if you moved it to another file, then:
+
+```
+Sections that were moved:
+
+[ Section A ]
+```
+
+Use the relative style to link to the new file so that the versioned docs continue to work.
+
+
+## Writing Documentation - Specification
+
+The `huggingface/accelerate` documentation follows the
+[Google documentation](https://sphinxcontrib-napoleon.readthedocs.io/en/latest/example_google.html) style for docstrings,
+although we can write them directly in Markdown.
+
+### Adding a new tutorial
+
+Adding a new tutorial or section is done in two steps:
+
+- Add a new file under `./source`. This file can either be ReStructuredText (.rst) or Markdown (.md).
+- Link that file in `./source/_toctree.yml` on the correct toc-tree.
+
+Make sure to put your new file under the proper section. It's unlikely to go in the first section (*Get Started*), so
+depending on the intended targets (beginners, more advanced users, or researchers) it should go in sections two, three, or
+four.
+
+### Writing source documentation
+
+Values that should be put in `code` should either be surrounded by backticks: \`like so\`. Note that argument names
+and objects like True, None, or any strings should usually be put in `code`.
+
+When mentioning a class, function, or method, it is recommended to use our syntax for internal links so that our tool
+adds a link to its documentation with this syntax: \[\`XXXClass\`\] or \[\`function\`\]. This requires the class or
+function to be in the main package.
+
+If you want to create a link to some internal class or function, you need to
+provide its path. For instance: \[\`utils.gather\`\]. This will be converted into a link with
+`utils.gather` in the description. To get rid of the path and only keep the name of the object you are
+linking to in the description, add a ~: \[\`~utils.gather\`\] will generate a link with `gather` in the description.
+
+The same works for methods so you can either use \[\`XXXClass.method\`\] or \[~\`XXXClass.method\`\].
+
+#### Defining arguments in a method
+
+Arguments should be defined with the `Args:` (or `Arguments:` or `Parameters:`) prefix, followed by a line return and
+an indentation. The argument should be followed by its type, with its shape if it is a tensor, a colon, and its
+description:
+
+```
+ Args:
+ n_layers (`int`): The number of layers of the model.
+```
+
+If the description is too long to fit in one line (more than 119 characters in total), another indentation is necessary
+before writing the description after the argument.
+
+Finally, to maintain uniformity if any *one* description is too long to fit on one line, the
+rest of the parameters should follow suit and have an indention before their description.
+
+Here's an example showcasing everything so far:
+
+```
+ Args:
+ gradient_accumulation_steps (`int`, *optional*, default to 1):
+ The number of steps that should pass before gradients are accumulated. A number > 1 should be combined with `Accelerator.accumulate`.
+ cpu (`bool`, *optional*):
+ Whether or not to force the script to execute on CPU. Will ignore GPU available if set to `True` and force the execution on one process only.
+```
+
+For optional arguments or arguments with defaults we follow the following syntax: imagine we have a function with the
+following signature:
+
+```
+def my_function(x: str = None, a: float = 1):
+```
+
+then its documentation should look like this:
+
+```
+ Args:
+ x (`str`, *optional*):
+ This argument controls ... and has a description longer than 119 chars.
+ a (`float`, *optional*, defaults to 1):
+ This argument is used to ... and has a description longer than 119 chars.
+```
+
+Note that we always omit the "defaults to \`None\`" when None is the default for any argument. Also note that even
+if the first line describing your argument type and its default gets long, you can't break it on several lines. You can
+however write as many lines as you want in the indented description (see the example above with `input_ids`).
+
+#### Writing a multi-line code block
+
+Multi-line code blocks can be useful for displaying examples. They are done between two lines of three backticks as usual in Markdown:
+
+
+````
+```python
+# first line of code
+# second line
+# etc
+```
+````
+
+#### Writing a return block
+
+The return block should be introduced with the `Returns:` prefix, followed by a line return and an indentation.
+The first line should be the type of the return, followed by a line return. No need to indent further for the elements
+building the return.
+
+Here's an example of a single value return:
+
+```
+ Returns:
+ `List[int]`: A list of integers in the range [0, 1] --- 1 for a special token, 0 for a sequence token.
+```
+
+Here's an example of a tuple return, comprising several objects:
+
+```
+ Returns:
+ `tuple(torch.FloatTensor)` comprising various elements depending on the configuration ([`BertConfig`]) and inputs:
+ - ** loss** (*optional*, returned when `masked_lm_labels` is provided) `torch.FloatTensor` of shape `(1,)` --
+ Total loss is the sum of the masked language modeling loss and the next sequence prediction (classification) loss.
+ - **prediction_scores** (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`) --
+ Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
+```
+
+## Styling the docstring
+
+We have an automatic script running with the `make style` comment that will make sure that:
+- the docstrings fully take advantage of the line width
+- all code examples are formatted using black, like the code of the Transformers library
+
+This script may have some weird failures if you made a syntax mistake or if you uncover a bug. Therefore, it's
+recommended to commit your changes before running `make style`, so you can revert the changes done by that script
+easily.
+
+## Writing documentation examples
+
+The syntax for Example docstrings can look as follows:
+
+```
+ Example:
+
+ ```python
+ >>> import time
+ >>> from accelerate import Accelerator
+ >>> accelerator = Accelerator()
+ >>> if accelerator.is_main_process:
+ ... time.sleep(2)
+ >>> else:
+ ... print("I'm waiting for the main process to finish its sleep...")
+ >>> accelerator.wait_for_everyone()
+ >>> # Should print on every process at the same time
+ >>> print("Everyone is here")
+ ```
+```
+
+The docstring should give a minimal, clear example of how the respective function
+is to be used in inference and also include the expected (ideally sensible)
+output.
+Often, readers will try out the example before even going through the function
+or class definitions. Therefore, it is of utmost importance that the example
+works as expected.
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/_toctree.yml b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..209b035f5e375ec5f09a1e99895587fc5c8cba1d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/_toctree.yml
@@ -0,0 +1,135 @@
+- sections:
+ - local: index
+ title: 🤗 Accelerate
+ - local: basic_tutorials/install
+ title: Installation
+ - local: quicktour
+ title: Quicktour
+ title: Getting started
+- sections:
+ - local: basic_tutorials/overview
+ title: Overview
+ - local: basic_tutorials/migration
+ title: Add Accelerate to your code
+ - local: basic_tutorials/execution
+ title: Execution process
+ - local: basic_tutorials/tpu
+ title: TPU training
+ - local: basic_tutorials/launch
+ title: Launching Accelerate scripts
+ - local: basic_tutorials/notebook
+ title: Launching distributed training from Jupyter Notebooks
+ title: Tutorials
+- sections:
+ - isExpanded: true
+ sections:
+ - local: usage_guides/explore
+ title: Start Here!
+ - local: usage_guides/model_size_estimator
+ title: Model memory estimator
+ - local: usage_guides/quantization
+ title: Model quantization
+ - local: usage_guides/tracking
+ title: Experiment trackers
+ - local: usage_guides/profiler
+ title: Profiler
+ - local: usage_guides/checkpoint
+ title: Checkpointing
+ - local: basic_tutorials/troubleshooting
+ title: Troubleshoot
+ - local: usage_guides/training_zoo
+ title: Example Zoo
+ title: Accelerate
+ - isExpanded: true
+ sections:
+ - local: usage_guides/gradient_accumulation
+ title: Gradient accumulation
+ - local: usage_guides/local_sgd
+ title: Local SGD
+ - local: usage_guides/low_precision_training
+ title: Low precision (FP8) training
+ - local: usage_guides/deepspeed
+ title: DeepSpeed
+ - local: usage_guides/deepspeed_multiple_model
+ title: Using multiple models with DeepSpeed
+ - local: usage_guides/ddp_comm_hook
+ title: DDP Communication Hooks
+ - local: usage_guides/fsdp
+ title: Fully Sharded Data Parallel
+ - local: usage_guides/megatron_lm
+ title: Megatron-LM
+ - local: usage_guides/sagemaker
+ title: Amazon SageMaker
+ - local: usage_guides/mps
+ title: Apple M1 GPUs
+ - local: usage_guides/intel_cpu
+ title: Intel CPU
+ - local: usage_guides/gaudi
+ title: Intel Gaudi
+ - local: usage_guides/compilation
+ title: Compilation
+ title: Training
+ - isExpanded: true
+ sections:
+ - local: usage_guides/big_modeling
+ title: Big Model Inference
+ - local: usage_guides/distributed_inference
+ title: Distributed inference
+ title: Inference
+ title: How to guides
+- sections:
+ - local: concept_guides/internal_mechanism
+ title: Accelerate's internal mechanism
+ - local: concept_guides/big_model_inference
+ title: Loading big models into memory
+ - local: concept_guides/performance
+ title: Comparing performance across distributed setups
+ - local: concept_guides/deferring_execution
+ title: Executing and deferring jobs
+ - local: concept_guides/gradient_synchronization
+ title: Gradient synchronization
+ - local: concept_guides/fsdp_and_deepspeed
+ title: FSDP vs DeepSpeed
+ - local: concept_guides/fsdp1_vs_fsdp2
+ title: FSDP1 vs FSDP2
+ - local: concept_guides/context_parallelism
+ title: Context parallelism
+ - local: concept_guides/sequence_parallelism
+ title: Sequence parallelism
+ - local: concept_guides/low_precision_training
+ title: Low precision training methods
+ - local: concept_guides/training_tpu
+ title: Training on TPUs
+ title: Concepts and fundamentals
+- sections:
+ - local: package_reference/accelerator
+ title: Accelerator
+ - local: package_reference/state
+ title: Stateful classes
+ - local: package_reference/cli
+ title: The Command Line
+ - local: package_reference/torch_wrappers
+ title: DataLoaders, Optimizers, Schedulers
+ - local: package_reference/tracking
+ title: Experiment trackers
+ - local: package_reference/launchers
+ title: Launchers
+ - local: package_reference/deepspeed
+ title: DeepSpeed utilities
+ - local: package_reference/logging
+ title: Logging
+ - local: package_reference/big_modeling
+ title: Working with large models
+ - local: package_reference/inference
+ title: Pipeline parallelism
+ - local: package_reference/kwargs
+ title: Kwargs handlers
+ - local: package_reference/fp8
+ title: FP8
+ - local: package_reference/utilities
+ title: Utility functions and classes
+ - local: package_reference/megatron_lm
+ title: Megatron-LM utilities
+ - local: package_reference/fsdp
+ title: Fully Sharded Data Parallel utilities
+ title: "Reference"
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/execution.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/execution.md
new file mode 100644
index 0000000000000000000000000000000000000000..4874f4439938ef18997f2cfb78f55c83fae70965
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/execution.md
@@ -0,0 +1,128 @@
+
+
+# Execution process
+
+When working with distributed training systems, it is important to manage how and when processes are executed across GPUs. Some processes are completed faster than others, and some processes shouldn't begin if others haven't finished yet. Accelerate provides tools for orchestrating when processes are executed to ensure everything remains synchronized across all devices.
+
+This tutorial will teach you how to execute a process on only one machine and how to delay execution until all processes have reached a certain point.
+
+## Execute on one process
+
+Certain code only needs to be run once on a given machine, such as printing a log statement or only displaying one progress bar on the local main process.
+
+
+
+
+You should use `accelerator.is_local_main_process` to indicate code that should only be executed once.
+
+```py
+from tqdm.auto import tqdm
+
+progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+```
+
+You could also wrap a statement with `accelerator.is_local_main_process`.
+
+> [!TIP]
+> For standalone `print` statements that aren't wrapped in `accelerator.is_local_main_process`, replace `print` with Accelerate's [`~Accelerator.print`] method to only print once per process.
+
+```py
+if accelerator.is_local_main_process:
+ print("Accelerate is the best")
+```
+
+
+
+
+For a function that should only be executed once, use [`~Accelerator.on_local_main_process`].
+
+```py
+@accelerator.on_local_main_process
+def do_my_thing():
+ "Something done once per server"
+ do_thing_once_per_server()
+```
+
+
+
+
+You could also direct Accelerate to execute code once across *all processes* regardless of the number of machines. This is useful if you're uploading a final model to the Hub.
+
+
+
+
+You should use `accelerator.is_main_process` to indicate code that should only be executed once across all processes.
+
+```py
+if accelerator.is_main_process:
+ repo.push_to_hub()
+```
+
+
+
+
+For a function that should only be executed once across all processes, use [`~Accelerator.on_main_process`].
+
+```py
+@accelerator.on_main_process
+def do_my_thing():
+ "Something done once per server"
+ do_thing_once()
+```
+
+
+
+
+## Execute on a specific process
+
+Accelerate can also help you execute functions that should only be executed on a specific process or a local process index.
+
+
+
+
+Use the [`~Accelerator.on_process`] method and specify the process index to execute a function on.
+
+```py
+@accelerator.on_process(process_index=0)
+def do_my_thing():
+ "Something done on process index 0"
+ do_thing_on_index_zero()
+```
+
+
+
+
+Use the [`~Accelerator.on_local_process`] method and specify the local process index to execute a function on.
+
+```py
+@accelerator.on_local_process(local_process_idx=0)
+def do_my_thing():
+ "Something done on process index 0 on each server"
+ do_thing_on_index_zero_on_each_server()
+```
+
+
+
+
+## Defer execution
+
+When you run your script on several GPUs at the same time, some code may be executed faster than others. You might need to wait for all processes to reach a certain point before executing the next set of instructions. For instance, you shouldn’t save a model before making sure every process is done with training.
+
+To do this, add [`~Accelerator.wait_for_everyone`] in your code. This blocks all processes that have finished first from continuing until all remaining processes have reached the same point (this has no effect if you're running on a single GPU or CPU).
+
+```py
+accelerator.wait_for_everyone()
+```
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/install.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/install.md
new file mode 100644
index 0000000000000000000000000000000000000000..6d409257a4e1e22f4b76332b25dafc1a0021ca4e
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/install.md
@@ -0,0 +1,114 @@
+
+
+# Installation
+
+Before you start, you will need to setup your environment, install the appropriate packages, and configure Accelerate. Accelerate is tested on **Python 3.8+**.
+
+Accelerate is available on pypi and conda, as well as on GitHub. Details to install from each are below:
+
+## pip
+
+To install Accelerate from pypi, perform:
+
+```bash
+pip install accelerate
+```
+
+## conda
+
+Accelerate can also be installed with conda with:
+
+```bash
+conda install -c conda-forge accelerate
+```
+
+## Source
+
+New features are added every day that haven't been released yet. To try them out yourself, install
+from the GitHub repository:
+
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+If you're working on contributing to the library or wish to play with the source code and see live
+results as you run the code, an editable version can be installed from a locally-cloned version of the
+repository:
+
+```bash
+git clone https://github.com/huggingface/accelerate
+cd accelerate
+pip install -e .
+```
+
+## Configuration
+
+After installing, you need to configure Accelerate for how the current system is setup for training.
+To do so run the following and answer the questions prompted to you:
+
+```bash
+accelerate config
+```
+
+To write a barebones configuration that doesn't include options such as DeepSpeed configuration or running on TPUs, you can quickly run:
+
+```bash
+python -c "from accelerate.utils import write_basic_config; write_basic_config(mixed_precision='fp16')"
+```
+
+Accelerate will automatically utilize the maximum number of GPUs available and set the mixed precision mode.
+
+To check that your configuration looks fine, run:
+
+```bash
+accelerate env
+```
+
+An example output is shown below, which describes two GPUs on a single machine with no mixed precision being used:
+
+
+```bash
+- `Accelerate` version: 1.2.0.dev0
+- Platform: Linux-6.8.0-47-generic-x86_64-with-glibc2.35
+- `accelerate` bash location: /home/zach/miniconda3/envs/accelerate/bin/accelerate
+- Python version: 3.10.13
+- Numpy version: 1.26.4
+- PyTorch version (GPU?): 2.5.1+cu124 (True)
+- PyTorch XPU available: False
+- PyTorch NPU available: False
+- PyTorch MLU available: False
+- PyTorch MUSA available: False
+- System RAM: 187.91 GB
+- GPU type: NVIDIA GeForce RTX 4090
+- `Accelerate` default config:
+ - compute_environment: LOCAL_MACHINE
+ - distributed_type: MULTI_GPU
+ - mixed_precision: no
+ - use_cpu: False
+ - debug: False
+ - num_processes: 2
+ - machine_rank: 0
+ - num_machines: 1
+ - gpu_ids: all
+ - rdzv_backend: static
+ - same_network: True
+ - main_training_function: main
+ - enable_cpu_affinity: False
+ - downcast_bf16: no
+ - tpu_use_cluster: False
+ - tpu_use_sudo: False
+ - tpu_env: []
+```
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/launch.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/launch.md
new file mode 100644
index 0000000000000000000000000000000000000000..449d72d668541b8f4678076c5015d3d66a7a4899
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/launch.md
@@ -0,0 +1,235 @@
+
+
+# Launching Accelerate scripts
+
+In the previous tutorial, you were introduced to how to modify your current training script to use Accelerate.
+The final version of that code is shown below:
+
+```python
+from accelerate import Accelerator
+
+accelerator = Accelerator()
+
+model, optimizer, training_dataloader, scheduler = accelerator.prepare(
+ model, optimizer, training_dataloader, scheduler
+)
+
+for batch in training_dataloader:
+ optimizer.zero_grad()
+ inputs, targets = batch
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets)
+ accelerator.backward(loss)
+ optimizer.step()
+ scheduler.step()
+```
+
+But how do you run this code and have it utilize the special hardware available to it?
+
+First, you should rewrite the above code into a function, and make it callable as a script. For example:
+
+```diff
+ from accelerate import Accelerator
+
++ def main():
+ accelerator = Accelerator()
+
+ model, optimizer, training_dataloader, scheduler = accelerator.prepare(
+ model, optimizer, training_dataloader, scheduler
+ )
+
+ for batch in training_dataloader:
+ optimizer.zero_grad()
+ inputs, targets = batch
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets)
+ accelerator.backward(loss)
+ optimizer.step()
+ scheduler.step()
+
++ if __name__ == "__main__":
++ main()
+```
+
+Next, you need to launch it with `accelerate launch`.
+
+
+
+ It's recommended you run `accelerate config` before using `accelerate launch` to configure your environment to your liking.
+ Otherwise Accelerate will use very basic defaults depending on your system setup.
+
+
+
+
+## Using accelerate launch
+
+Accelerate has a special CLI command to help you launch your code in your system through `accelerate launch`.
+This command wraps around all of the different commands needed to launch your script on various platforms, without you having to remember what each of them is.
+
+
+
+ If you are familiar with launching scripts in PyTorch yourself such as with `torchrun`, you can still do this. It is not required to use `accelerate launch`.
+
+
+
+You can launch your script quickly by using:
+
+```bash
+accelerate launch {script_name.py} --arg1 --arg2 ...
+```
+
+Just put `accelerate launch` at the start of your command, and pass in additional arguments and parameters to your script afterward like normal!
+
+Since this runs the various torch spawn methods, all of the expected environment variables can be modified here as well.
+For example, here is how to use `accelerate launch` with a single GPU:
+
+```bash
+# for cuda device:
+CUDA_VISIBLE_DEVICES="0" accelerate launch {script_name.py} --arg1 --arg2 ...
+# for xpu device:
+ZE_AFFINITY_MASK="0" accelerate launch {script_name.py} --arg1 --arg2 ...
+```
+
+You can also use `accelerate launch` without performing `accelerate config` first, but you may need to manually pass in the right configuration parameters.
+In this case, Accelerate will make some hyperparameter decisions for you, e.g., if GPUs are available, it will use all of them by default without the mixed precision.
+Here is how you would use all GPUs and train with mixed precision disabled:
+
+```bash
+accelerate launch --multi_gpu {script_name.py} {--arg1} {--arg2} ...
+```
+
+Or by specifying a number of GPUs to use:
+
+```bash
+accelerate launch --num_processes=2 {script_name.py} {--arg1} {--arg2} ...
+```
+
+To get more specific you should pass in the needed parameters yourself. For instance, here is how you
+would also launch that same script on two GPUs using mixed precision while avoiding all of the warnings:
+
+```bash
+accelerate launch --multi_gpu --mixed_precision=fp16 --num_processes=2 {script_name.py} {--arg1} {--arg2} ...
+```
+
+For a complete list of parameters you can pass in, run:
+
+```bash
+accelerate launch -h
+```
+
+
+
+ Even if you are not using Accelerate in your code, you can still use the launcher for starting your scripts!
+
+
+
+For a visualization of this difference, that earlier `accelerate launch` on multi-gpu would look something like so with `torchrun`:
+
+```bash
+MIXED_PRECISION="fp16" torchrun --nproc_per_node=2 --nnodes=1 {script_name.py} {--arg1} {--arg2} ...
+```
+
+You can also launch your script utilizing the launch CLI as a python module itself, enabling the ability to pass in other python-specific
+launching behaviors. To do so, use `accelerate.commands.launch` instead of `accelerate launch`:
+
+```bash
+python -m accelerate.commands.launch --num_processes=2 {script_name.py} {--arg1} {--arg2}
+```
+
+If you want to execute the script with any other python flags, you can pass them in as well similar to `-m`, such as
+the below example enabling unbuffered stdout and stderr:
+
+```bash
+python -u -m accelerate.commands.launch --num_processes=2 {script_name.py} {--arg1} {--arg2}
+```
+
+
+
+ You can run your code on CPU as well! This is helpful for debugging and testing purposes on toy models and datasets.
+
+```bash
+accelerate launch --cpu {script_name.py} {--arg1} {--arg2}
+```
+
+
+
+## Why you should always use `accelerate config`
+
+Why is it useful to the point you should **always** run `accelerate config`?
+
+Remember that earlier call to `accelerate launch` as well as `torchrun`?
+Post configuration, to run that script with the needed parts you just need to use `accelerate launch` outright, without passing anything else in:
+
+```bash
+accelerate launch {script_name.py} {--arg1} {--arg2} ...
+```
+
+
+## Custom Configurations
+
+As briefly mentioned earlier, `accelerate launch` should be mostly used through combining set configurations
+made with the `accelerate config` command. These configs are saved to a `default_config.yaml` file in your cache folder for Accelerate.
+This cache folder is located at (with decreasing order of priority):
+
+- The content of your environment variable `HF_HOME` suffixed with `accelerate`.
+- If it does not exist, the content of your environment variable `XDG_CACHE_HOME` suffixed with
+ `huggingface/accelerate`.
+- If this does not exist either, the folder `~/.cache/huggingface/accelerate`.
+
+To have multiple configurations, the flag `--config_file` can be passed to the `accelerate launch` command paired
+with the location of the custom yaml.
+
+An example yaml may look something like the following for two GPUs on a single machine using `fp16` for mixed precision:
+```yaml
+compute_environment: LOCAL_MACHINE
+deepspeed_config: {}
+distributed_type: MULTI_GPU
+fsdp_config: {}
+machine_rank: 0
+main_process_ip: null
+main_process_port: null
+main_training_function: main
+mixed_precision: fp16
+num_machines: 1
+num_processes: 2
+use_cpu: false
+```
+
+Launching a script from the location of that custom yaml file looks like the following:
+```bash
+accelerate launch --config_file {path/to/config/my_config_file.yaml} {script_name.py} {--arg1} {--arg2} ...
+```
+
+## Multi-node training
+Multi-node training with Accelerate is similar to [multi-node training with torchrun](https://pytorch.org/tutorials/intermediate/ddp_series_multinode.html). The simplest way to launch a multi-node training run is to do the following:
+
+- Copy your codebase and data to all nodes. (or place them on a shared filesystem)
+- Setup your python packages on all nodes.
+- Run `accelerate config` on the main single node first. After specifying the number of nodes, you will be asked to specify the rank of each node (this will be 0 for the main/master node), along with the IP address and port for the main process. This is required for the worker nodes to communicate with the main process. Afterwards, you can copy or send this config file across all of your nodes, changing the `machine_rank` to 1, 2,3, etc. to avoid having to run the command (or just follow their directions directly for launching with `torchrun` as well)
+
+Once you have done this, you can start your multi-node training run by running `accelerate launch` (or `torchrun`) on all nodes.
+
+
+ It is required that the command be ran on all nodes for everything to start, not just running it from the main node. You can use something like SLURM or a different process executor to wrap around this requirement and call everything from a single command.
+
+
+
+
+ It is recommended to use the intranet IP of your main node over the public IP for better latency. This is the `192.168.x.x` or the `172.x.x.x` address you see when you run `hostname -I` on the main node.
+
+
+
+To get a better idea about multi-node training, check out our example for [multi-node training with FSDP](https://huggingface.co/blog/ram-efficient-pytorch-fsdp).
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/migration.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/migration.md
new file mode 100644
index 0000000000000000000000000000000000000000..e8b50d0a8a2ec7ddd38bf90fd4ddbf668303ee74
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/migration.md
@@ -0,0 +1,224 @@
+
+
+# Add Accelerate to your code
+
+Each distributed training framework has their own way of doing things which can require writing a lot of custom code to adapt it to your PyTorch training code and training environment. Accelerate offers a friendly way to interface with these distributed training frameworks without having to learn the specific details of each one. Accelerate takes care of those details for you, so you can focus on the training code and scale it to any distributed training environment.
+
+In this tutorial, you'll learn how to adapt your existing PyTorch code with Accelerate and get you on your way toward training on distributed systems with ease! You'll start with a basic PyTorch training loop (it assumes all the training objects like `model` and `optimizer` have been setup already) and progressively integrate Accelerate into it.
+
+```python
+device = "cuda"
+model.to(device)
+
+for batch in training_dataloader:
+ optimizer.zero_grad()
+ inputs, targets = batch
+ inputs = inputs.to(device)
+ targets = targets.to(device)
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets)
+ loss.backward()
+ optimizer.step()
+ scheduler.step()
+```
+
+## Accelerator
+
+The [`Accelerator`] is the main class for adapting your code to work with Accelerate. It knows about the distributed setup you're using such as the number of different processes and your hardware type. This class also provides access to many of the necessary methods for enabling your PyTorch code to work in any distributed training environment and for managing and executing processes across devices.
+
+That's why you should always start by importing and creating an [`Accelerator`] instance in your script.
+
+```python
+from accelerate import Accelerator
+
+accelerator = Accelerator()
+```
+
+The [`Accelerator`] also knows which device to move your PyTorch objects to, so it is recommended to let Accelerate handle this for you.
+
+```diff
+- device = "cuda"
++ device = accelerator.device
+ model.to(device)
+```
+
+## Prepare PyTorch objects
+
+Next, you need to prepare your PyTorch objects (model, optimizer, scheduler, etc.) for distributed training. The [`~Accelerator.prepare`] method takes care of placing your model in the appropriate container (like single GPU or multi-GPU) for your training setup, adapting the optimizer and scheduler to use Accelerate's [`~optimizer.AcceleratedOptimizer`] and [`~scheduler.AcceleratedScheduler`], and creating a new dataloader that can be sharded across processes.
+
+> [!TIP]
+> Accelerate only prepares objects that inherit from their respective PyTorch classes such as `torch.optim.Optimizer`.
+
+The PyTorch objects are returned in the same order they're sent.
+
+```py
+model, optimizer, training_dataloader, scheduler = accelerator.prepare(
+ model, optimizer, training_dataloader, scheduler
+)
+```
+
+## Training loop
+
+Finally, remove the `to(device)` calls to the inputs and targets in the training loop because Accelerate's DataLoader classes automatically places them on the right device. You should also replace the usual `backward()` pass with Accelerate's [`~Accelerator.backward`] method which scales the gradients for you and uses the appropriate `backward()` method depending on your distributed setup (for example, DeepSpeed or Megatron).
+
+```diff
+- inputs = inputs.to(device)
+- targets = targets.to(device)
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets)
+- loss.backward()
++ accelerator.backward(loss)
+```
+
+Put everything together and your new Accelerate training loop should now look like this!
+
+```python
+from accelerate import Accelerator
+accelerator = Accelerator()
+
+device = accelerator.device
+model, optimizer, training_dataloader, scheduler = accelerator.prepare(
+ model, optimizer, training_dataloader, scheduler
+)
+
+for batch in training_dataloader:
+ optimizer.zero_grad()
+ inputs, targets = batch
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets)
+ accelerator.backward(loss)
+ optimizer.step()
+ scheduler.step()
+```
+
+## Training features
+
+Accelerate offers additional features - like gradient accumulation, gradient clipping, mixed precision training and more - you can add to your script to improve your training run. Let's explore these three features.
+
+### Gradient accumulation
+
+Gradient accumulation enables you to train on larger batch sizes by accumulating the gradients over multiple batches before updating the weights. This can be useful for getting around memory limitations. To enable this feature in Accelerate, specify the `gradient_accumulation_steps` parameter in the [`Accelerator`] class and add the [`~Accelerator.accumulate`] context manager to your script.
+
+```diff
++ accelerator = Accelerator(gradient_accumulation_steps=2)
+ model, optimizer, training_dataloader = accelerator.prepare(model, optimizer, training_dataloader)
+
+ for input, label in training_dataloader:
++ with accelerator.accumulate(model):
+ predictions = model(input)
+ loss = loss_function(predictions, label)
+ accelerator.backward(loss)
+ optimizer.step()
+ scheduler.step()
+ optimizer.zero_grad()
+```
+
+### Gradient clipping
+
+Gradient clipping is a technique to prevent "exploding gradients", and Accelerate offers:
+
+* [`~Accelerator.clip_grad_value_`] to clip gradients to a minimum and maximum value
+* [`~Accelerator.clip_grad_norm_`] for normalizing gradients to a certain value
+
+### Mixed precision
+
+Mixed precision accelerates training by using a lower precision data type like fp16 (half-precision) to calculate the gradients. For the best performance with Accelerate, the loss should be computed inside your model (like in Transformers models) because computations outside of the model are computed in full precision.
+
+Set the mixed precision type to use in the [`Accelerator`], and then use the [`~Accelerator.autocast`] context manager to automatically cast the values to the specified data type.
+
+> [!WARNING]
+> Accelerate enables automatic mixed precision, so [`~Accelerator.autocast`] is only needed if there are other mixed precision operations besides those performed on loss by [`~Accelerator.backward`] which already handles the scaling.
+
+```diff
++ accelerator = Accelerator(mixed_precision="fp16")
++ with accelerator.autocast():
+ loss = complex_loss_function(outputs, target)
+```
+
+## Save and load
+
+Accelerate can also save and load a *model* once training is complete or you can also save the model and optimizer *state* which could be useful for resuming training.
+
+### Model
+
+Once all processes are complete, unwrap the model with the [`~Accelerator.unwrap_model`] method before saving it because the [`~Accelerator.prepare`] method wrapped your model into the proper interface for distributed training. If you don't unwrap the model, saving the model state dictionary also saves any potential extra layers from the larger model and you won't be able to load the weights back into your base model.
+
+You should use the [`~Accelerator.save_model`] method to unwrap and save the model state dictionary. This method can also save a model into sharded checkpoints or into the [safetensors](https://hf.co/docs/safetensors/index) format.
+
+
+
+
+```py
+accelerator.wait_for_everyone()
+accelerator.save_model(model, save_directory)
+```
+
+
+
+For models from the [Transformers](https://hf.co/docs/transformers/index) library, save the model with the [`~transformers.PreTrainedModel.save_pretrained`] method so that it can be reloaded with the [`~transformers.PreTrainedModel.from_pretrained`] method.
+
+```py
+from transformers import AutoModel
+
+unwrapped_model = accelerator.unwrap_model(model)
+unwrapped_model.save_pretrained(
+ "path/to/my_model_directory",
+ is_main_process=accelerator.is_main_process,
+ save_function=accelerator.save,
+)
+
+model = AutoModel.from_pretrained("path/to/my_model_directory")
+```
+
+
+
+To load your weights, use the [`~Accelerator.unwrap_model`] method to unwrap the model first before loading the weights. All model parameters are references to tensors, so this loads your weights inside `model`.
+
+```py
+unwrapped_model = accelerator.unwrap_model(model)
+path_to_checkpoint = os.path.join(save_directory,"pytorch_model.bin")
+unwrapped_model.load_state_dict(torch.load(path_to_checkpoint))
+```
+
+
+
+
+Set `safe_serialization=True` to save the model in the safetensor format.
+
+```py
+accelerator.wait_for_everyone()
+accelerator.save_model(model, save_directory, max_shard_size="1GB", safe_serialization=True)
+```
+
+To load a sharded checkpoint or a safetensor formatted checkpoint, use the [`~accelerate.load_checkpoint_in_model`] method. This method allows you to load a checkpoint onto a specific device.
+
+```py
+load_checkpoint_in_model(unwrapped_model, save_directory, device_map={"":device})
+```
+
+
+
+
+### State
+
+During training, you may want to save the current state of the model, optimizer, random generators, and potentially learning rate schedulers so they can be restored in the *same script*. You should add the [`~Accelerator.save_state`] and [`~Accelerator.load_state`] methods to your script to save and load states.
+
+To further customize where and how states are saved through [`~Accelerator.save_state`], use the [`~utils.ProjectConfiguration`] class. For example, if `automatic_checkpoint_naming` is enabled, each saved checkpoint is stored at `Accelerator.project_dir/checkpoints/checkpoint_{checkpoint_number}`.
+
+Any other stateful items to be stored should be registered with the [`~Accelerator.register_for_checkpointing`] method so they can be saved and loaded. Every object passed to this method to be stored must have a `load_state_dict` and `state_dict` function.
+
+> [!TIP]
+> If you have [`torchdata>=0.8.0`](https://github.com/pytorch/data/tree/main) installed, you can additionally pass `use_stateful_dataloader=True` into your [`~utils.DataLoaderConfiguration`]. This extends Accelerate's DataLoader classes with a `load_state_dict` and `state_dict` function, and makes it so `Accelerator.save_state` and `Accelerator.load_state` also track how far into the training dataset it has read when persisting the model.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/notebook.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/notebook.md
new file mode 100644
index 0000000000000000000000000000000000000000..508a1216eda606de78193ce6b9a0106819b0455c
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/notebook.md
@@ -0,0 +1,476 @@
+
+
+# Launching distributed training from Jupyter Notebooks
+
+This tutorial teaches you how to fine tune a computer vision model with 🤗 Accelerate from a Jupyter Notebook on a distributed system.
+You will also learn how to setup a few requirements needed for ensuring your environment is configured properly, your data has been prepared properly, and finally how to launch training.
+
+
+
+ This tutorial is also available as a Jupyter Notebook [here](https://github.com/huggingface/notebooks/blob/main/examples/accelerate_examples/simple_cv_example.ipynb)
+
+
+
+## Configuring the Environment
+
+Before any training can be performed, an Accelerate config file must exist in the system. Usually this can be done by running the following in a terminal and answering the prompts:
+
+```bash
+accelerate config
+```
+
+However, if general defaults are fine and you are *not* running on a TPU, Accelerate has a utility to quickly write your GPU configuration into a config file via [`utils.write_basic_config`].
+
+The following code will restart Jupyter after writing the configuration, as CUDA code was called to perform this.
+
+
+
+ CUDA can't be initialized more than once on a multi-GPU system. It's fine to debug in the notebook and have calls to CUDA, but in order to finally train a full cleanup and restart will need to be performed.
+
+
+
+```python
+import os
+from accelerate.utils import write_basic_config
+
+write_basic_config() # Write a config file
+os._exit(00) # Restart the notebook
+```
+
+## Preparing the Dataset and Model
+
+Next you should prepare your dataset. As mentioned earlier, great care should be taken when preparing the `DataLoaders` and model to make sure that **nothing** is put on *any* GPU.
+
+If you do, it is recommended to put that specific code into a function and call that from within the notebook launcher interface, which will be shown later.
+
+Make sure the dataset is downloaded based on the directions [here](https://github.com/huggingface/accelerate/tree/main/examples#simple-vision-example)
+
+```python
+import os, re, torch, PIL
+import numpy as np
+
+from torch.optim.lr_scheduler import OneCycleLR
+from torch.utils.data import DataLoader, Dataset
+from torchvision.transforms import Compose, RandomResizedCrop, Resize, ToTensor
+
+from accelerate import Accelerator
+from accelerate.utils import set_seed
+from timm import create_model
+```
+
+First you need to create a function to extract the class name based on a filename:
+
+```python
+import os
+
+data_dir = "../../images"
+fnames = os.listdir(data_dir)
+fname = fnames[0]
+print(fname)
+```
+
+```python out
+beagle_32.jpg
+```
+
+In the case here, the label is `beagle`. Using regex you can extract the label from the filename:
+
+```python
+import re
+
+
+def extract_label(fname):
+ stem = fname.split(os.path.sep)[-1]
+ return re.search(r"^(.*)_\d+\.jpg$", stem).groups()[0]
+```
+
+```python
+extract_label(fname)
+```
+
+And you can see it properly returned the right name for our file:
+
+```python out
+"beagle"
+```
+
+Next a `Dataset` class should be made to handle grabbing the image and the label:
+
+```python
+class PetsDataset(Dataset):
+ def __init__(self, file_names, image_transform=None, label_to_id=None):
+ self.file_names = file_names
+ self.image_transform = image_transform
+ self.label_to_id = label_to_id
+
+ def __len__(self):
+ return len(self.file_names)
+
+ def __getitem__(self, idx):
+ fname = self.file_names[idx]
+ raw_image = PIL.Image.open(fname)
+ image = raw_image.convert("RGB")
+ if self.image_transform is not None:
+ image = self.image_transform(image)
+ label = extract_label(fname)
+ if self.label_to_id is not None:
+ label = self.label_to_id[label]
+ return {"image": image, "label": label}
+```
+
+Now to build the dataset. Outside the training function you can find and declare all the filenames and labels and use them as references inside the
+launched function:
+
+```python
+fnames = [os.path.join("../../images", fname) for fname in fnames if fname.endswith(".jpg")]
+```
+
+Next gather all the labels:
+
+```python
+all_labels = [extract_label(fname) for fname in fnames]
+id_to_label = list(set(all_labels))
+id_to_label.sort()
+label_to_id = {lbl: i for i, lbl in enumerate(id_to_label)}
+```
+
+Next, you should make a `get_dataloaders` function that will return your built dataloaders for you. As mentioned earlier, if data is automatically
+sent to the GPU or a TPU device when building your `DataLoaders`, they must be built using this method.
+
+```python
+def get_dataloaders(batch_size: int = 64):
+ "Builds a set of dataloaders with a batch_size"
+ random_perm = np.random.permutation(len(fnames))
+ cut = int(0.8 * len(fnames))
+ train_split = random_perm[:cut]
+ eval_split = random_perm[cut:]
+
+ # For training a simple RandomResizedCrop will be used
+ train_tfm = Compose([RandomResizedCrop((224, 224), scale=(0.5, 1.0)), ToTensor()])
+ train_dataset = PetsDataset([fnames[i] for i in train_split], image_transform=train_tfm, label_to_id=label_to_id)
+
+ # For evaluation a deterministic Resize will be used
+ eval_tfm = Compose([Resize((224, 224)), ToTensor()])
+ eval_dataset = PetsDataset([fnames[i] for i in eval_split], image_transform=eval_tfm, label_to_id=label_to_id)
+
+ # Instantiate dataloaders
+ train_dataloader = DataLoader(train_dataset, shuffle=True, batch_size=batch_size, num_workers=4)
+ eval_dataloader = DataLoader(eval_dataset, shuffle=False, batch_size=batch_size * 2, num_workers=4)
+ return train_dataloader, eval_dataloader
+```
+
+Finally, you should import the scheduler to be used later:
+
+```python
+from torch.optim.lr_scheduler import CosineAnnealingLR
+```
+
+## Writing the Training Function
+
+Now you can build the training loop. [`notebook_launcher`] works by passing in a function to call that will be ran across the distributed system.
+
+Here is a basic training loop for the animal classification problem:
+
+
+
+ The code has been split up to allow for explanations on each section. A full version that can be copy and pasted will be available at the end
+
+
+
+
+```python
+def training_loop(mixed_precision="fp16", seed: int = 42, batch_size: int = 64):
+ set_seed(seed)
+ accelerator = Accelerator(mixed_precision=mixed_precision)
+```
+
+First you should set the seed and create an [`Accelerator`] object as early in the training loop as possible.
+
+
+
+ If training on the TPU, your training loop should take in the model as a parameter and it should be instantiated
+ outside of the training loop function. See the [TPU best practices](../concept_guides/training_tpu)
+ to learn why
+
+
+
+Next you should build your dataloaders and create your model:
+
+```python
+ train_dataloader, eval_dataloader = get_dataloaders(batch_size)
+ model = create_model("resnet50d", pretrained=True, num_classes=len(label_to_id))
+```
+
+
+
+ You build the model here so that the seed also controls the new weight initialization
+
+
+
+As you are performing transfer learning in this example, the encoder of the model starts out frozen so the head of the model can be
+trained only initially:
+
+```python
+ for param in model.parameters():
+ param.requires_grad = False
+ for param in model.get_classifier().parameters():
+ param.requires_grad = True
+```
+
+Normalizing the batches of images will make training a little faster:
+
+```python
+ mean = torch.tensor(model.default_cfg["mean"])[None, :, None, None]
+ std = torch.tensor(model.default_cfg["std"])[None, :, None, None]
+```
+
+To make these constants available on the active device, you should set it to the Accelerator's device:
+
+```python
+ mean = mean.to(accelerator.device)
+ std = std.to(accelerator.device)
+```
+
+Next instantiate the rest of the PyTorch classes used for training:
+
+```python
+ optimizer = torch.optim.Adam(params=model.parameters(), lr=3e-2 / 25)
+ lr_scheduler = OneCycleLR(optimizer=optimizer, max_lr=3e-2, epochs=5, steps_per_epoch=len(train_dataloader))
+```
+
+Before passing everything to [`~Accelerator.prepare`].
+
+
+
+ There is no specific order to remember, you just need to unpack the objects in the same order you gave them to the prepare method.
+
+
+
+```python
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+```
+
+Now train the model:
+
+```python
+ for epoch in range(5):
+ model.train()
+ for batch in train_dataloader:
+ inputs = (batch["image"] - mean) / std
+ outputs = model(inputs)
+ loss = torch.nn.functional.cross_entropy(outputs, batch["label"])
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+```
+
+The evaluation loop will look slightly different compared to the training loop. The number of elements passed as well as the overall
+total accuracy of each batch will be added to two constants:
+
+```python
+ model.eval()
+ accurate = 0
+ num_elems = 0
+```
+
+Next you have the rest of your standard PyTorch loop:
+
+```python
+ for batch in eval_dataloader:
+ inputs = (batch["image"] - mean) / std
+ with torch.no_grad():
+ outputs = model(inputs)
+ predictions = outputs.argmax(dim=-1)
+```
+
+Before finally the last major difference.
+
+When performing distributed evaluation, the predictions and labels need to be passed through
+[`~Accelerator.gather`] so that all of the data is available on the current device and a properly calculated metric can be achieved:
+
+```python
+ accurate_preds = accelerator.gather(predictions) == accelerator.gather(batch["label"])
+ num_elems += accurate_preds.shape[0]
+ accurate += accurate_preds.long().sum()
+```
+
+Now you just need to calculate the actual metric for this problem, and you can print it on the main process using [`~Accelerator.print`]:
+
+```python
+ eval_metric = accurate.item() / num_elems
+ accelerator.print(f"epoch {epoch}: {100 * eval_metric:.2f}")
+```
+
+A full version of this training loop is available below:
+
+```python
+def training_loop(mixed_precision="fp16", seed: int = 42, batch_size: int = 64):
+ set_seed(seed)
+ # Initialize accelerator
+ accelerator = Accelerator(mixed_precision=mixed_precision)
+ # Build dataloaders
+ train_dataloader, eval_dataloader = get_dataloaders(batch_size)
+
+ # Instantiate the model (you build the model here so that the seed also controls new weight initializations)
+ model = create_model("resnet50d", pretrained=True, num_classes=len(label_to_id))
+
+ # Freeze the base model
+ for param in model.parameters():
+ param.requires_grad = False
+ for param in model.get_classifier().parameters():
+ param.requires_grad = True
+
+ # You can normalize the batches of images to be a bit faster
+ mean = torch.tensor(model.default_cfg["mean"])[None, :, None, None]
+ std = torch.tensor(model.default_cfg["std"])[None, :, None, None]
+
+ # To make these constants available on the active device, set it to the accelerator device
+ mean = mean.to(accelerator.device)
+ std = std.to(accelerator.device)
+
+ # Instantiate the optimizer
+ optimizer = torch.optim.Adam(params=model.parameters(), lr=3e-2 / 25)
+
+ # Instantiate the learning rate scheduler
+ lr_scheduler = OneCycleLR(optimizer=optimizer, max_lr=3e-2, epochs=5, steps_per_epoch=len(train_dataloader))
+
+ # Prepare everything
+ # There is no specific order to remember, you just need to unpack the objects in the same order you gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # Now you train the model
+ for epoch in range(5):
+ model.train()
+ for batch in train_dataloader:
+ inputs = (batch["image"] - mean) / std
+ outputs = model(inputs)
+ loss = torch.nn.functional.cross_entropy(outputs, batch["label"])
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ model.eval()
+ accurate = 0
+ num_elems = 0
+ for batch in eval_dataloader:
+ inputs = (batch["image"] - mean) / std
+ with torch.no_grad():
+ outputs = model(inputs)
+ predictions = outputs.argmax(dim=-1)
+ accurate_preds = accelerator.gather(predictions) == accelerator.gather(batch["label"])
+ num_elems += accurate_preds.shape[0]
+ accurate += accurate_preds.long().sum()
+
+ eval_metric = accurate.item() / num_elems
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}: {100 * eval_metric:.2f}")
+```
+
+## Using the notebook_launcher
+
+All that's left is to use the [`notebook_launcher`].
+
+You pass in the function, the arguments (as a tuple), and the number of processes to train on. (See the [documentation](../package_reference/launchers) for more information)
+
+```python
+from accelerate import notebook_launcher
+```
+
+```python
+args = ("fp16", 42, 64)
+notebook_launcher(training_loop, args, num_processes=2)
+```
+
+In the case of running on multiple nodes, you need to set up a Jupyter session at each node and run the launching cell at the same time.
+
+For an environment containing 2 nodes (computers) with 8 GPUs each and the main computer with an IP address of "172.31.43.8", it would look like so:
+
+```python
+notebook_launcher(training_loop, args, master_addr="172.31.43.8", node_rank=0, num_nodes=2, num_processes=8)
+```
+
+And in the second Jupyter session on the other machine:
+
+
+
+ Notice how the `node_rank` has changed
+
+
+
+```python
+notebook_launcher(training_loop, args, master_addr="172.31.43.8", node_rank=1, num_nodes=2, num_processes=8)
+```
+
+In the case of running on the TPU, it would look like so:
+
+```python
+model = create_model("resnet50d", pretrained=True, num_classes=len(label_to_id))
+
+args = (model, "fp16", 42, 64)
+notebook_launcher(training_loop, args, num_processes=8)
+```
+
+To launch the training process with elasticity, enabling fault tolerance, you can use the `elastic_launch` feature provided by PyTorch. This requires setting additional parameters such as `rdzv_backend` and `max_restarts`. Here is an example of how to use `notebook_launcher` with elastic capabilities:
+
+```python
+notebook_launcher(
+ training_loop,
+ args,
+ num_processes=2,
+ max_restarts=3
+)
+```
+
+As it's running it will print the progress as well as state how many devices you ran on. This tutorial was ran with two GPUs:
+
+```python out
+Launching training on 2 GPUs.
+epoch 0: 88.12
+epoch 1: 91.73
+epoch 2: 92.58
+epoch 3: 93.90
+epoch 4: 94.71
+```
+
+And that's it!
+
+Please note that [`notebook_launcher`] ignores the Accelerate config file, to launch based on the config use:
+
+```bash
+accelerate launch
+```
+
+## Debugging
+
+A common issue when running the `notebook_launcher` is receiving a CUDA has already been initialized issue. This usually stems
+from an import or prior code in the notebook that makes a call to the PyTorch `torch.cuda` sublibrary. To help narrow down what went wrong,
+you can launch the `notebook_launcher` with `ACCELERATE_DEBUG_MODE=yes` in your environment and an additional check
+will be made when spawning that a regular process can be created and utilize CUDA without issue. (Your CUDA code can still be ran afterwards).
+
+## Conclusion
+
+This notebook showed how to perform distributed training from inside of a Jupyter Notebook. Some key notes to remember:
+
+- Make sure to save any code that use CUDA (or CUDA imports) for the function passed to [`notebook_launcher`]
+- Set the `num_processes` to be the number of devices used for training (such as number of GPUs, CPUs, TPUs, etc)
+- If using the TPU, declare your model outside the training loop function
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/overview.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/overview.md
new file mode 100644
index 0000000000000000000000000000000000000000..0ac665104ae9ae5a4feb63af5d60ad636f1d54a2
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/overview.md
@@ -0,0 +1,24 @@
+
+
+# Overview
+
+Welcome to the Accelerate tutorials! These introductory guides will help catch you up to speed on working with Accelerate.
+You'll learn how to modify your code to have it work with the API seamlessly, how to launch your script properly,
+and more!
+
+These tutorials assume some basic knowledge of Python and familiarity with the PyTorch framework.
+
+If you have any questions about Accelerate, feel free to join and ask the community on our [forum](https://discuss.huggingface.co/c/accelerate/18).
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/tpu.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/tpu.md
new file mode 100644
index 0000000000000000000000000000000000000000..f4780e3fe5f555b35d3d867fe0da071b49eb3c6a
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/tpu.md
@@ -0,0 +1,38 @@
+
+
+# TPU training
+
+A [TPU (Tensor Processing Unit)](https://cloud.google.com/tpu/docs/intro-to-tpu) is a type of hardware specifically designed for training models efficiently. Accelerate supports TPU training, but there are a few things you should be aware of, namely graph compilation. This tutorial briefly discusses compilation, and for more details, take a look at the [Training on TPUs with Accelerate](../concept_guides/training_tpu) guide.
+
+## Compilation
+
+A TPU creates a graph of all the operations in the training step such as the forward pass, backward pass and optimizer step. This is why the first training step always takes a while because building and compiling this graph takes time. But once compilation is complete, it is cached and all subsequent steps are much faster.
+
+The key is to avoid compiling your code again or else training is super slow. This means all your operations must be exactly the same:
+
+* all tensors in your batches must have the same length (for example, no dynamic padding for NLP tasks)
+* your code must be static (for example, no layers with for loops that have different lengths depending on the input such as a LSTM)
+
+## Weight tying
+
+A common language model design is to tie the weights of the embedding and softmax layers. However, moving the model to a TPU (either yourself or passing it to the [`~Accelerator.prepare`] method) breaks the weight tying and you'll need to retie the weights.
+
+To add special behavior (like weight tying) in your script for TPUs, set [`~Accelerator.distributed_type`] to `DistributedType.TPU` first. Then you can use the [`~transformers.PreTrainedModel.tie_weights`] method to tie the weights.
+
+```py
+if accelerator.distributed_type == DistributedType.TPU:
+ model.tie_weights()
+```
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/troubleshooting.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/troubleshooting.md
new file mode 100644
index 0000000000000000000000000000000000000000..9ca8f8d57230fb6a5456c037fa84dcfa77827b96
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/basic_tutorials/troubleshooting.md
@@ -0,0 +1,211 @@
+
+
+# Troubleshoot
+
+This guide provides solutions to some issues you might encounter when using Accelerate. Not all errors are covered because Accelerate is an active library that is continuously evolving and there are many different use cases and distributed training setups. If the solutions described here don't help with your specific error, please take a look at the [Ask for help](#ask-for-help) section to learn where and how to get help.
+
+## Logging
+
+Logging can help you identify where an error is coming from. In a distributed setup with multiple processes, logging can be a challenge, but Accelerate provides the [`~accelerate.logging`] utility to ensure logs are synchronized.
+
+To troubleshoot an issue, use [`~accelerate.logging`] instead of the standard Python [`logging`](https://docs.python.org/3/library/logging.html#module-logging) module. Set the verbosity level (`INFO`, `DEBUG`, `WARNING`, `ERROR`, `CRITICAL`) with the `log_level` parameter, and then you can either:
+
+1. Export the `log_level` as the `ACCELERATE_LOG_LEVEL` environment variable.
+2. Pass the `log_level` directly to `get_logger`.
+
+For example, to set `log_level="INFO"`:
+
+```py
+from accelerate.logging import get_logger
+
+logger = get_logger(__name__, log_level="DEBUG")
+```
+
+By default, the log is called on main processes only. To call it on all processes, pass `main_process_only=False`.
+If a log should be called on all processes and in order, also pass `in_order=True`.
+
+```py
+from accelerate.logging import get_logger
+
+logger = get_logger(__name__, log_level="DEBUG")
+# log all processes
+logger.debug("thing_to_log", main_process_only=False)
+# log all processes in order
+logger.debug("thing_to_log", main_process_only=False, in_order=True)
+```
+
+## Hanging code and timeout errors
+
+There can be many reasons why your code is hanging. Let's take a look at how to solve some of the most common issues that can cause your code to hang.
+
+### Mismatched tensor shapes
+
+Mismatched tensor shapes is a common issue that can cause your code to hang for a significant amount of time on a distributed setup.
+
+When running scripts in a distributed setup, functions such as [`Accelerator.gather`] and [`Accelerator.reduce`] are necessary to grab tensors across devices to collectively perform operations on them. These (and other) functions rely on `torch.distributed` to perform a `gather` operation, which requires tensors to have the **exact same shape** across all processes. When the tensor shapes don't match, your code hangs and you'll eventually hit a timeout exception.
+
+You can use Accelerate's operational debug mode to immediately catch this issue. We recommend enabling this mode during the `accelerate config` setup, but you can also enable it from the CLI, as an environment variable, or by manually editing the `config.yaml` file.
+
+
+
+
+```bash
+accelerate launch --debug {my_script.py} --arg1 --arg2
+```
+
+
+
+
+If enabling debug mode as an environment variable, you don't need to call `accelerate launch`.
+
+```bash
+ACCELERATE_DEBUG_MODE="1" torchrun {my_script.py} --arg1 --arg2
+```
+
+
+
+
+Add `debug: true` to your `config.yaml` file.
+
+```yaml
+compute_environment: LOCAL_MACHINE
+debug: true
+```
+
+
+
+
+Once you enable debug mode, you should get a traceback that points to the tensor shape mismatch issue.
+
+```py
+Traceback (most recent call last):
+ File "/home/zach_mueller_huggingface_co/test.py", line 18, in
+ main()
+ File "/home/zach_mueller_huggingface_co/test.py", line 15, in main
+ broadcast_tensor = broadcast(tensor)
+ File "/home/zach_mueller_huggingface_co/accelerate/src/accelerate/utils/operations.py", line 303, in wrapper
+accelerate.utils.operations.DistributedOperationException:
+
+Cannot apply desired operation due to shape mismatches. All shapes across devices must be valid.
+
+Operation: `accelerate.utils.operations.broadcast`
+Input shapes:
+ - Process 0: [1, 5]
+ - Process 1: [1, 2, 5]
+```
+
+### Early stopping
+
+For early stopping in distributed training, if each process has a specific stopping condition (e.g. validation loss), it may not be synchronized across all processes. As a result, a break can happen on process 0 but not on process 1 which will cause your code to hang indefinitely until a timeout occurs.
+
+If you have early stopping conditionals, use the `set_trigger` and `check_trigger` methods to make sure all the processes
+are ended correctly.
+
+```py
+# Assume `should_do_breakpoint` is a custom defined function that returns a conditional,
+# and that conditional might be true only on process 1
+if should_do_breakpoint(loss):
+ accelerator.set_trigger()
+
+# Later in the training script when we need to check for the breakpoint
+if accelerator.check_trigger():
+ break
+```
+
+### Low kernel versions on Linux
+
+On Linux with kernel version < 5.5, hanging processes have been reported. To avoid this problem, upgrade your system to a later kernel version.
+
+### MPI
+
+If your distributed CPU training job using MPI is hanging, ensure that you have
+[passwordless SSH](https://www.open-mpi.org/faq/?category=rsh#ssh-keys) setup (using keys) between the nodes. This means
+that for all nodes in your hostfile, you should to be able to SSH from one node to another without being prompted for a password.
+
+Next, try to run the `mpirun` command as a sanity check. For example, the command below should print out the
+hostnames for each of the nodes.
+
+```bash
+mpirun -f hostfile -n {number of nodes} -ppn 1 hostname
+```
+
+## Out-of-Memory
+
+One of the most frustrating errors when it comes to running training scripts is hitting "Out-of-Memory" on devices like CUDA, XPU or CPU. The entire script needs to be restarted and any progress is lost.
+
+To address this problem, Accelerate provides the [`find_executable_batch_size`] utility that is heavily based on [toma](https://github.com/BlackHC/toma).
+This utility retries code that fails due to OOM (out-of-memory) conditions and automatically lowers batch sizes. For each OOM condition, the algorithm decreases the batch size by half and retries the code until it succeeds.
+
+To use [`find_executable_batch_size`], restructure your training function to include an inner function with `find_executable_batch_size` and build your dataloaders inside it. At a minimum, this only takes 4 new lines of code.
+
+
+
+The inner function **must** take batch size as the first parameter, but we do not pass one to it when called. The wrapper will handle this for you. Any object (models, optimizers) that consumes device memory and is passed to the [`Accelerator`] also **must** be declared inside the inner function.
+
+
+
+```diff
+def training_function(args):
+ accelerator = Accelerator()
+
++ @find_executable_batch_size(starting_batch_size=args.batch_size)
++ def inner_training_loop(batch_size):
++ nonlocal accelerator # Ensure they can be used in our context
++ accelerator.free_memory() # Free all lingering references
+ model = get_model()
+ model.to(accelerator.device)
+ optimizer = get_optimizer()
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size)
+ lr_scheduler = get_scheduler(
+ optimizer,
+ num_training_steps=len(train_dataloader)*num_epochs
+ )
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+ train(model, optimizer, train_dataloader, lr_scheduler)
+ validate(model, eval_dataloader)
++ inner_training_loop()
+```
+
+## Non-reproducible results between device setups
+
+If you changed the device setup and observe different model performance, it is likely you didn't update your script when moving from one setup to another. Even if you're using the same script with the same batch size, the results will still be different on a TPU, multi-GPU, and single GPU.
+
+For example, if you were training on a single GPU with a batch size of 16 and you move to a dual GPU setup, you need to change the batch size to 8 to have the same effective batch size. This is because when training with Accelerate, the batch size passed to the dataloader is the **batch size per GPU**.
+
+To make sure you can reproduce the results between the setups, make sure to use the same seed, adjust the batch size accordingly, and consider scaling the learning rate.
+
+For more details and a quick reference for batch sizes, check out the [Comparing performance between different device setups](../concept_guides/performance) guide.
+
+## Performance issues on different GPUs
+
+If your multi-GPU setup consists of different GPUs, you may encounter some performance issues:
+
+- There may be an imbalance in GPU memory between the GPUs. In this case, the GPU with the smaller memory will limit the batch size or the size of the model that can be loaded onto the GPUs.
+- If you are using GPUs with different performance profiles, the performance will be driven by the slowest GPU you are using because the other GPUs will have to wait for it to complete its workload.
+
+Vastly different GPUs within the same setup can lead to performance bottlenecks.
+
+## Ask for help
+
+If none of the solutions and advice here helped resolve your issue, you can always reach out to the community and Accelerate team for help.
+
+- Ask for help on the Hugging Face forums by posting your question in the [Accelerate category](https://discuss.huggingface.co/c/accelerate/18). Make sure to write a descriptive post with relevant context about your setup and reproducible code to maximize the likelihood that your problem is solved!
+
+- Post a question on [Discord](http://hf.co/join/discord), and let the team and the community help you.
+
+- Create an Issue on the Accelerate [GitHub repository](https://github.com/huggingface/accelerate/issues) if you think you've found a bug related to the library. Include context regarding the bug and details about your distributed setup to help us better figure out what's wrong and how we can fix it.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/big_model_inference.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/big_model_inference.md
new file mode 100644
index 0000000000000000000000000000000000000000..27cb0430772257aab7404a8a8f43c2772859ad21
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/big_model_inference.md
@@ -0,0 +1,341 @@
+
+
+# Loading big models into memory
+
+When loading a pre-trained model in PyTorch, the usual workflow looks like this:
+
+```py
+import torch
+
+my_model = ModelClass(...)
+state_dict = torch.load(checkpoint_file)
+my_model.load_state_dict(state_dict)
+```
+
+In plain English, those steps are:
+1. Create the model with randomly initialized weights
+2. Load the model weights (in a dictionary usually called a state dict) from the disk
+3. Load those weights inside the model
+
+While this works very well for regularly sized models, this workflow has some clear limitations when we deal with a huge model: in step 1, we load a full version of the model in RAM, and spend some time randomly initializing the weights (which will be discarded in step 3). In step 2, we load another full version of the model in RAM, with the pre-trained weights. If you're loading a model with 6 billion parameters, this means you will need 24GB of RAM for each copy of the model, so 48GB in total (half of it to load the model in FP16).
+
+
+
+This API is quite new and still in its experimental stage. While we strive to provide a stable API, it's possible some small parts of the public API will change in the future.
+
+
+
+## How the Process Works: A Quick Overview
+
+
+
+## How the Process Works: Working with Code
+
+### Instantiating an empty model
+
+The first tool Accelerate introduces to help with big models is a context manager [`init_empty_weights`] that helps you initialize a model without using any RAM so that step 1 can be done on models of any size. Here is how it works:
+
+```py
+from accelerate import init_empty_weights
+
+with init_empty_weights():
+ my_model = ModelClass(...)
+```
+
+For instance:
+
+```py
+with init_empty_weights():
+ model = nn.Sequential(*[nn.Linear(10000, 10000) for _ in range(1000)])
+```
+
+initializes an empty model with a bit more than 100B parameters. Behind the scenes, this relies on the meta device introduced in PyTorch 1.9. During the initialization under the context manager, each time a parameter is created, it is instantly moved to that device.
+
+
+
+ You can't move a model initialized like this on CPU or another device directly, since it doesn't have any data. It's also very likely that a forward pass with that empty model will fail, as not all operations are supported on the meta device.
+
+
+
+### Sharded checkpoints
+
+It's possible your model is so big that even a single copy won't fit in RAM. That doesn't mean it can't be loaded: if you have one or several GPUs, this is more memory available to store your model. In this case, it's better if your checkpoint is split into several smaller files that we call checkpoint shards.
+
+Accelerate will handle sharded checkpoints as long as you follow the following format: your checkpoint should be in a folder, with several files containing the partial state dicts, and there should be an index in the JSON format that contains a dictionary mapping parameter names to the file containing their weights. You can easily shard your model with [`~Accelerator.save_model`]. For instance, we could have a folder containing:
+
+```bash
+first_state_dict.bin
+index.json
+second_state_dict.bin
+```
+
+with index.json being the following file:
+
+```
+{
+ "linear1.weight": "first_state_dict.bin",
+ "linear1.bias": "first_state_dict.bin",
+ "linear2.weight": "second_state_dict.bin",
+ "linear2.bias": "second_state_dict.bin"
+}
+```
+
+and `first_state_dict.bin` containing the weights for `"linear1.weight"` and `"linear1.bias"`, `second_state_dict.bin` the ones for `"linear2.weight"` and `"linear2.bias"`
+
+### Loading weights
+
+The second tool Accelerate introduces is a function [`load_checkpoint_and_dispatch`], that will allow you to load a checkpoint inside your empty model. This supports full checkpoints (a single file containing the whole state dict) as well as sharded checkpoints. It will also automatically dispatch those weights across the devices you have available (GPUs, CPU RAM), so if you are loading a sharded checkpoint, the maximum RAM usage will be the size of the biggest shard.
+
+If you want to use big model inference with Transformers models, check out this [documentation](https://huggingface.co/docs/transformers/main/en/main_classes/model#large-model-loading).
+
+Here is how we can use this to load the [GPT2-1.5B](https://huggingface.co/marcsun13/gpt2-xl-linear-sharded) model.
+
+Let's download the sharded version of this model.
+
+```bash
+pip install huggingface_hub
+```
+
+```py
+from huggingface_hub import snapshot_download
+checkpoint = "marcsun13/gpt2-xl-linear-sharded"
+weights_location = snapshot_download(repo_id=checkpoint)
+```
+
+In order to initialize the model, we will use the library minGPT.
+
+```bash
+git clone https://github.com/karpathy/minGPT.git
+pip install minGPT/
+```
+
+```py
+from accelerate import init_empty_weights
+from mingpt.model import GPT
+
+model_config = GPT.get_default_config()
+model_config.model_type = 'gpt2-xl'
+model_config.vocab_size = 50257
+model_config.block_size = 1024
+
+with init_empty_weights():
+ model = GPT(model_config)
+```
+
+Then, load the checkpoint we just downloaded with:
+
+```py
+from accelerate import load_checkpoint_and_dispatch
+
+model = load_checkpoint_and_dispatch(
+ model, checkpoint=weights_location, device_map="auto", no_split_module_classes=['Block']
+)
+```
+
+By passing `device_map="auto"`, we tell Accelerate to determine automatically where to put each layer of the model depending on the available resources:
+- first, we use the maximum space available on the GPU(s)
+- if we still need space, we store the remaining weights on the CPU
+- if there is not enough RAM, we store the remaining weights on the hard drive as memory-mapped tensors
+
+
+#### `no_split_module_classes`
+
+This parameter will indicate that some of the modules with the name `"Block"` should not be split across different devices. You should set here all blocks that
+include a residual connection of some kind.
+
+
+#### The `device_map`
+
+You can see the `device_map` that Accelerate picked by accessing the `hf_device_map` attribute of your model:
+
+```py
+model.hf_device_map
+```
+
+```python out
+{'transformer.wte': 0,
+ 'transformer.wpe': 0,
+ 'transformer.drop': 0,
+ 'transformer.h.0': 0,
+ ...
+ 'transformer.h.21': 0,
+ 'transformer.h.22': 1,
+ 'transformer.h.23': 1,
+ 'transformer.h.24': 1,
+ ...
+ 'transformer.h.47': 1,
+ 'transformer.ln_f': 1,
+ 'lm_head': 1}
+ ```
+
+It's fully possible to create your own device map for the layers to use as well, specifying the GPU device to use (a number), `"cpu"`, or `"disk"` and pass this in:
+
+```python
+device_map = {
+ "transformer.wte": "cpu",
+ "transformer.wpe": 0,
+ "transformer.drop": "cpu",
+ "transformer.h.0": "disk"
+}
+
+model = load_checkpoint_and_dispatch(
+ model, checkpoint=weights_location, device_map=device_map
+)
+
+```
+
+### Run the model
+
+Now that we have done this, our model lies across several devices, and maybe the hard drive. But it can still be used as a regular PyTorch model:
+
+```py
+from mingpt.bpe import BPETokenizer
+tokenizer = BPETokenizer()
+inputs = tokenizer("Hello, my name is").to(0)
+
+outputs = model.generate(x1, max_new_tokens=10, do_sample=False)[0]
+tokenizer.decode(outputs.cpu().squeeze())
+```
+
+Behind the scenes, Accelerate added hooks to the model, so that:
+- at each layer, the inputs are put on the right device (so even if your model is spread across several GPUs, it works)
+- for the weights offloaded on the CPU, they are put on a GPU just before the forward pass and cleaned up just after
+- for the weights offloaded on the hard drive, they are loaded in RAM then put on a GPU just before the forward pass and cleaned up just after
+
+This way, your model can run for inference even if it doesn't fit on one of the GPUs or the CPU RAM!
+
+
+
+ This only supports the inference of your model, not training. Most of the computation happens behind `torch.no_grad()` context managers to avoid spending some GPU memory with intermediate activations.
+
+
+
+### Designing a device map
+
+You can let Accelerate handle the device map computation by setting `device_map` to one of the supported options (`"auto"`, `"balanced"`, `"balanced_low_0"`, `"sequential"`) or create one yourself if you want more control over where each layer should go.
+
+
+
+ You can derive all sizes of the model (and thus compute a `device_map`) on a model that is on the meta device.
+
+
+
+All the options will produce the same result when you don't have enough GPU memory to accommodate the whole model (which is to fit everything that can on the GPU, then offload weights on the CPU or even on the disk if there is not enough RAM).
+
+When you have more GPU memory available than the model size, here is the difference between each option:
+- `"auto"` and `"balanced"` evenly split the model on all available GPUs, making it possible for you to use a batch size greater than 1.
+- `"balanced_low_0"` evenly splits the model on all GPUs except the first one, and only puts on GPU 0 what does not fit on the others. This option is great when you need to use GPU 0 for some processing of the outputs, like when using the `generate` function for Transformers models
+- `"sequential"` will fit what it can on GPU 0, then move on GPU 1 and so forth (so won't use the last GPUs if it doesn't need to).
+
+
+
+ The options `"auto"` and `"balanced"` produce the same results for now, but the behavior of `"auto"` might change in the future if we find a strategy that makes more sense, while `"balanced"` will stay stable.
+
+
+
+First note that you can limit the memory used on each GPU by using the `max_memory` argument (available in [`infer_auto_device_map`] and in all functions using it). When setting `max_memory`, you should pass along a dictionary containing the GPU identifiers (for instance `0`, `1` etc.) and the `"cpu"` key for the maximum RAM you want to use for CPU offload. The values can either be an integer (in bytes) or a string representing a number with its unit, such as `"10GiB"` or `"10GB"`.
+
+Here is an example where we don't want to use more than 10GiB on each of the two GPUs and no more than 30GiB of CPU RAM for the model weights:
+
+```python
+from accelerate import infer_auto_device_map
+
+device_map = infer_auto_device_map(my_model, max_memory={0: "10GiB", 1: "10GiB", "cpu": "30GiB"})
+```
+
+
+
+ When a first allocation happens in PyTorch, it loads CUDA kernels which take about 1-2GB of memory depending on the GPU. Therefore you always have less usable memory than the actual size of the GPU. To see how much memory is actually used do `torch.ones(1).cuda()` and look at the memory usage.
+
+ Therefore when you create memory maps with `max_memory` make sure to adjust the available memory accordingly to avoid out-of-memory errors.
+
+
+
+Additionally, if you do some additional operations with your outputs without placing them back on the CPU (for instance inside the `generate` method of Transformers) and if you placed your inputs on a GPU, that GPU will consume more memory than the others (Accelerate always place the output back to the device of the input). Therefore if you would like to optimize the maximum batch size and you have many GPUs, give the first GPU less memory. For example, with BLOOM-176B on 8x80 A100 setup, the close-to-ideal map is:
+
+```python
+max_memory = {0: "30GIB", 1: "46GIB", 2: "46GIB", 3: "46GIB", 4: "46GIB", 5: "46GIB", 6: "46GIB", 7: "46GIB"}
+```
+as you can see we gave the remaining 7 GPUs ~50% more memory than GPU 0.
+
+If you opt to fully design the `device_map` yourself, it should be a dictionary with keys being module names of your model and values being a valid device identifier (for instance an integer for the GPUs) or `"cpu"` for CPU offload, `"disk"` for disk offload. The keys need to cover the whole model, you can then define your device map as you wish: for instance, if your model has two blocks (let's say `block1` and `block2`) which each contain three linear layers (let's say `linear1`, `linear2` and `linear3`), a valid device map can be:
+
+```python
+device_map = {"block1": 0, "block2": 1}
+```
+
+another one that is valid could be:
+
+```python
+device_map = {"block1": 0, "block2.linear1": 0, "block2.linear2": 1, "block2.linear3": 1}
+```
+
+On the other hand, this one is not valid as it does not cover every parameter of the model:
+
+```python
+device_map = {"block1": 0, "block2.linear1": 1, "block2.linear2": 1}
+```
+
+
+
+ To be the most efficient, make sure your device map puts the parameters on the GPUs in a sequential manner (e.g. don't put one of the first weights on GPU 0, then weights on GPU 1 and the last weight back to GPU 0) to avoid making many transfers of data between the GPUs.
+
+
+
+## CPU offload only
+
+If you want to offload your model on CPU, you can use [`cpu_offload`]. As a result, all parameters of the model will be offloaded and only one copy of the state dict of the model will be kept. During the forward pass, parameters will be extracted from that state dict and put on the execution device and passed as they are needed, then offloaded again.
+
+```python
+cpu_offload(model, execution_device)
+```
+
+You can also use [`cpu_offload_with_hook`]. This function will offloads a model on the CPU and puts it back to an execution device when executed. The difference with [`cpu_offload`] is that the model stays on the execution device after the forward and is only offloaded again when the `offload` method of the returned `hook` is called. Furthermore, [`cpu_offload_with_hook`] is more performant but less memory saving. It is useful for pipelines running a model in a loop:
+
+```python
+model_1, hook_1 = cpu_offload_with_hook(model_1, execution_device)
+model_2, hook_2 = cpu_offload_with_hook(model_2, execution_device, prev_module_hook=hook_1)
+model_3, hook_3 = cpu_offload_with_hook(model_3, execution_device, prev_module_hook=hook_2)
+
+hid_1 = model_1(input)
+for i in range(50):
+ # model1 is offloaded on the CPU at the first iteration, model 2 stays on the GPU for this whole loop.
+ hid_2 = model_2(hid_1)
+# model2 is offloaded to the CPU just before this forward.
+hid_3 = model_3(hid_3)
+
+# For model3, you need to manually call the hook offload method.
+hook_3.offload()
+```
+
+## Disk offload only
+
+To perform disk offload, you can use [`disk_offload`]. As a result, all parameters of the model will be offloaded as memory-mapped array in a given folder. During the forward pass, parameters will be accessed from that folder and put on the execution device passed as they are needed, then offloaded again.
+
+```python
+disk_offload(model, offload_dir, execution_device)
+```
+
+## Limits and further development
+
+We are aware of the current limitations in the API:
+
+- [`infer_auto_device_map`] (or `device_map="auto"` in [`load_checkpoint_and_dispatch`]) tries to maximize GPU and CPU RAM it sees available when you execute it. While PyTorch is very good at managing GPU RAM efficiently (and giving it back when not needed), it's not entirely true with Python and CPU RAM. Therefore, an automatically computed device map might be too intense on the CPU. Move a few modules to the disk device if you get crashes due to a lack of RAM.
+- [`infer_auto_device_map`] (or `device_map="auto"` in [`load_checkpoint_and_dispatch`]) attributes devices sequentially (to avoid moving things back and forth) so if your first layer is bigger than the size of the GPU you have, it will end up with everything on the CPU/Disk.
+- [`load_checkpoint_and_dispatch`] and [`load_checkpoint_in_model`] do not perform any check on the correctness of your state dict compared to your model at the moment (this will be fixed in a future version), so you may get some weird errors if trying to load a checkpoint with mismatched or missing keys.
+- The model parallelism used when your model is split on several GPUs is naive and not optimized, meaning that only one GPU works at a given time and the other sits idle.
+- When weights are offloaded on the CPU/hard drive, there is no pre-fetching (yet, we will work on this for future versions) which means the weights are put on the GPU when they are needed and not before.
+- Hard-drive offloading might be very slow if the hardware you run on does not have fast communication between disk and CPU (like NVMes).
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/context_parallelism.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/context_parallelism.md
new file mode 100644
index 0000000000000000000000000000000000000000..44a6a4b7b7b509f8254341552fd1c31c81e77afa
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/context_parallelism.md
@@ -0,0 +1,206 @@
+
+
+# Context Parallel in 🤗`accelerate`
+
+This guide will cover basics of using context parallelism in 🤗`accelerate`, for the more curious readers, we will also cover some technicalities in the later sections.
+
+See also the very related [Guide to Sequence Parallellism](./sequence_parallelism.md).
+
+## Why context parallelism?
+
+With the advent of large language models, and recently reasoning models, the sequence length has been growing rapidly. This, combined with quadratic memory complexity of attention, has led to a need for more efficient ways to train models with long sequences.
+With sequence length of 128k, the memory requirement of the attention matrix is `128k * 128k * 2 bytes * num_heads = ~32 GB * num_heads` for `bf16` precision, given vanilla attention implementation. Granted, with usage of `flash attention` or `SDPA` which do not materialize these attention weights, this decreases drastically, but the growth in memory requirements is still considerable.
+
+Context parallelism allows us to shard the inputs to the attention computation along the sequence dimension and compute the attention in parallel on multiple GPUs. With this, we can train models with long sequences, scaling potentially to 1M+ sequence length.
+
+## How to use context parallelism?
+
+```diff
+from accelerate.utils import ParallelismConfig, TorchContextParallelConfig
+
++ cp_config = TorchContextParallelConfig(
++ cp_comm_strategy="alltoall", # no need to use cp_config at all, if you want to use the default "allgather"
++ )
+
++ parallelism_config = ParallelismConfig(
++ cp_size=8,
++ cp_handler=cp_config, # or just cp_size=8, if you want to use the default "allgather"
++ )
+
+accelerator = Accelerator(
+ ...,
+ parallelism_config=parallelism_config,
+)
+```
+
+As with any other feature in 🤗`accelerate`, you can enable context parallelism also by passing the corresponding flags to `accelerate launch`.
+In this case, it's no different:
+
+```bash
+accelerate launch --parallelism-config-cp-size 8 --parallelism-config-cp-comm-strategy [allgather|alltoall] ...
+```
+
+> [!Tip]
+> You can also set the `cp_size` and `cp_comm_strategy` in the `accelerate config` command, which will save them in your `accelerate` configuration file, so you don't have to pass them every time you launch your script.
+
+> [!Tip]
+> Context parallelism is compatible with other parallelism strategies, such as data parallelism, tensor parallelism and FSDP2.
+> You can simply combine them by setting your parallelism sizes to the desired values, e.g. `--parallelism-config-dp-size 8 --parallelism-config-tp-size 2 --parallelism-config-cp-size 8`. Or you can use the `ParallelismConfig` class to set them programmatically.
+
+> [!Warning]
+> Context parallelism is tightly coupled with `FSDP2`, which you can learn more about in the [FSDP2 introduction](fsdp1_vs_fsdp2.md). Meaning, context parallelism only works if you use `FullyShardedDataParallelPlugin` or `--use-fsdp` with version set to 2 to your
+> program. If no `FSDP2` is used, error will be raised.
+
+> [!Warning]
+> Context parallelism works only with [SDPA](https://docs.pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html) and only with no mask or causal mask. We can't properly detect this for you, so it's your responsibility to ensure that you are using `SDPA` with no mask or causal mask. If you use any other attention implementation, it will raise an error.
+
+After enabling context parallelism with the methods mentioned above, you can then apply it to your training loop. We provide a thin wrapper around [`torch.distributed.tensor.experimental.context_parallel`](https://docs.pytorch.org/docs/stable/distributed.tensor.html#torch.distributed.tensor.experimental.context_parallel) that you can use in your training loop, that abstracts some of the complexity of using it (more on this later). To minimize the changes you have to do in your training loop, we provide a context manager that is a `noop` if context parallelism is not enabled, and applies the context parallelism if it is enabled. This way, you can use it in your training loop without changing any code based on your parallelism configuration.
+You can use it as follows:
+
+```python
+for batch in dataloader:
+ with accelerator.maybe_context_parallel(
+ buffers=[batch["input_ids"], batch["attention_mask"]],
+ buffer_seq_dims=[1, 1],
+ no_restore_buffers={batch["input_ids"], batch["labels"]},
+ ):
+ outputs = model(**batch)
+ ...
+```
+
+> [!Warning]
+> This context manager has to be recreated with each training step, as shown in the example above. It's crucial to do so.
+
+This can scale your context size to 1M+ sequence length potentially. Below, we showcase speed and memory usage of context parallelism for up-to 256k context size. We can see that when we double the context size and number of GPUs, we can achieve consistent memory usage, potentially enabling endless context length scaling.
+
+
+
+
+ Figure 1: Memory usage and speed of context parallelism for up-to 256k context size.
+
+
+> [!Tip]
+> These examples were created with a script you can find [in the examples folder](https://github.com/huggingface/accelerate/blob/main/examples/fsdp2/nd_parallel.py). To run the example on 8 H100 GPUs (128k sequence length), you can use the following command:
+> ```bash
+> accelerate launch --use-fsdp --fsdp-activation-checkpointing=TRUE examples/fsdp2/nd_parallel.py --cp-size=8 --sequence-length=128000
+> ```
+
+
+## Accelerate's interface
+
+The context manager takes a few arguments, that are used to configure the context parallelism.
+
+- `buffers`: This is a list of tensors that are to be sharded across the sequence dimension. These tensors are usually input ids, labels and attention mask.
+- `buffer_seq_dims`: This is a list of integers, that specify the sequence dimension of the buffers, in the order of the `buffers` list. If you pass `buffers=[input_ids, shift_labels]` with both having shape `[batch_size, sequence_length]`, you would pass `buffer_seq_dims=[1, 1]`.
+ as the sequence dimension is the second dimension of the tensors. This is required for correct computation of the model outputs.
+- `no_restore_buffers`: The implementation of context parallelism modifies the buffers in-place, converting them to `torch.distributed.tensor.Dtensor`s. After the context manager exits, a communication kernel would need to be launched to restore the buffers to their original state (usually all-gather). This takes some time, so it is recommended to pass the same tensors as in the `buffers` argument, to avoid unnecessary communication, unless you are sure that you need to use the buffers after the context manager exits.
+
+
+> [!Warning]
+> Context parallelism is not compatible with `labels` that are a copy of `input_ids`, which models from 🤗 transformers can shift to enable causal language modeling themselves.
+> Imagine this case:
+> labels = [l1, l2, l3, l4, ... li]
+> if we apply context parallelism, each rank would end up with a part of labels, such as this:
+> labels_rank_0 = [l1, l2], labels_rank_1 = [l3, l4], ...
+> after transformers modelling code shifts the labels, it would end up with:
+> labels_rank_0 = [l2, PAD], labels_rank_1 = [l3, PAD], ...
+> where `PAD` is a padding token. This would result in incorrect loss computation, as the labels are not aligned with the inputs anymore.
+> Because of this, you need to manually shift the labels before passing them in the model
+
+
+## Configurable options
+Accelerate provides only a single option to configure context parallelism (except for `cp_size`)
+
+- `cp_comm_strategy`: The rotation method to use for the shards. We strongly recommend keeping this as `"allgather"`, as it's very likely it will outperform `"alltoall"` in most cases.
+
+Context parallel size is rather self-explanatory, it's the number of ranks across which the inputs are to be-sharded.
+Context parallel shard rotation defines how the shards of the inputs are rotated across ranks. We'll cover the 2 options in more detail in the next section.
+
+You can see an end-to-end example in the [ND parallel example](https://github.com/huggingface/accelerate/blob/main/examples/fsdp2/nd_parallel.py) file, where you can train an 8B model with up-to 128k context length on a single 8xH100 node. Using multi-node training, you can scale this to 1M+ sequence length on multiple GPUs. You can also seamlessly combine it with other parallelism strategies to fit your needs.
+
+## Technical details
+
+> [!Tip]
+> This section is fairly technical, so if you don't need to learn the internals of context parallelism, you can skip it and start building 🚀
+
+We're going to be using word `shard` extensively in the following sections, so let's define it first. If we call tensor `sharded` across `Dth` dimension, across `N` ranks, we mean that this tensor is split into `N` parts, where each part of the tensor has shape `[..., D//N, ...]`.
+
+
+## So how does it work?
+
+Context parallelism works on sharding the `Q, K and V` matrices across the sequence dimension. Each rank has its assigned shard of `Q`, let's call it `Q_i`. This matrix stays only on this rank, during the whole computation. Similarly, each rank has its own shard of `K` and `V`, let's call them `K_i` and `V_i`. Then, each rank calculates attention with its own shard of `Q_i`, `K_i` and `V_i`, let's call it `attn_i`. During this computation, a communication kernel is launched to gather the `Ks` and `Vs` from all other ranks. What communication primitive is used, depends on the `context_parallel_shard_rotation` option.
+This way, each rank gets to calculate local attention, first with `Q_i`, `K_i` and `V_i`, then with `K_j` and `V_j` from all other ranks. As each rank holds `Q, K and V` matrices that are sharded across the sequence dimension, the resulting matrices are smaller and can fit on a single GPU.
+
+We can formalize this in the following pseudocode:
+```python
+comm_kernel = {"allgather": allgather, "alltoall": alltoall}[context_parallel_shard_rotation]
+Qi, Ki, Vi = shard(Q, K, V, seq_dim)
+attn[i] = attn(Qi, Ki, Vi)
+for j in range(context_parallel_size):
+ Kj, Vj = comm_kernel()
+ attn[j] = attn(Qi, Kj, Vj) # [batch, num_heads, seq_len // context_parallel_size, head_dim]
+
+final_attn = combine(attn)
+```
+
+## all-to-all vs all-gather
+
+### all-gather
+So what's the difference between all-to-all and all-gather? With all-gather, the communication is very simple. After (well, before, as it usually takes longer) we compute the local attention `attn_i` we launch an all-gather to gather all other `Ks` and `Vs` from all other ranks. As this communication is done, each rank has all the `Ks` and `Vs` from all other ranks, and can compute the attention with them sequentially.
+In ideal scenario, all-gather finishes in the exact moment as the calculation of `attn_i` is done. However, this never happens in practice, so the ideal real overlap is achieved when the full `attn_i` is overlapped with a part of the communication, then to start the computation with `K_j` and `V_j`, we wait for the all-gather to finish.
+
+### all-to-all
+All-to-all, or sometimes called `ring-rotation` utilizes a ring-like communication pattern. After concluding `attn_i` computation, an all-to-all is launched to send `K_i` and `V_i` to the neighbouring ranks. We then repeat this `context_parallel_size-1` times, so that each rank sees all the shards of `K` and `V` from all other ranks once. In ideal scenario, we prefetch shards `K_i+1` and `V_i+1` from the neighbouring rank and this communication is exactly overlapped with computation of our current `attn_i`. Again, realistically, this perfect overlap doesn't ever happen. Given the nature of this approach, if we don't achieve perfect overlap, the penalty is way larger than with all-gather.
+
+## How to choose the right rotation method?
+In theory, all-to-all should be the better choice. Though in practice, it rarely is. Therefore, we default to all-gather, as it's more likely to achieve better performance. Extensive [benchmarks](https://discuss.pytorch.org/t/distributed-w-torchtitan-breaking-barriers-training-long-context-llms-with-1m-sequence-length-in-pytorch-using-context-parallel/215082) from the `torchtitan` team also show that all-to-all rarely outperforms all-gather. Though, we still provide both options, as you might find one to be better for your use case.
+
+You can directly see this issue in the profiler output in the image below:
+
+
+
+ Figure 1: In red you can see the idle time, while we wait for the all-to-all kernel to finish. Highlighted in the first blue bar, you can see that it takes ~250us to finish, which is repeated N-1 times for each attention call, where N is the context parallel size.
+
+
+
+## Why only FSDP2?
+
+We only support context parallelism with `FSDP2`, as we create a joint mesh of `context_parallel_size` and `dp_shard_size` to
+utilize its full potential.
+How it works is: we shard the model across the joint mesh of size `cp_size*dp_shard_size`, which maximizes the memory savings.
+This is a "free lunch" of sorts, as `FSDP` communication is fully overlapped with the computation of attention, as shown in the images below.
+
+
+
+
+ Figure 2: In blue rectangles (Stream 23), you can see that the pre-fetch of `FSDP` shard is fully overlapped with the computation of attention (Stream 7), while in red rectangles (Stream 24), you can see that the all-gather kernel results in a bubble of idle time, in which our compute stream (7) is idle.
+
+
+In the figure above, you can also note the difference between all-to-all and all-gather. While in all-to-all (Figure 1), we launch a communication kernel N-1 times for each attention call, in all-gather (Figure 2), we launch a communication kernel only once. This results in a bigger bubble, but it only happens once per attention call, while in all-to-all, it happens N-1 times.
+
+## Data dispatching in joint mesh
+
+We make sure to dispatch the same batch of data to the whole `cp` subgroup, so that the results are correct. (Meaning each rank in `cp` subgroup gets the same batch of data.) However, we also dispatch different batches to each rank of `dp_shard` group.
+Imagine it like this:
+```
+# 8 GPUS, --dp_shard_size 4, --cp_size 2
+# mesh = [[0, 1], [2, 3], [4, 5], [6, 7]]
+# model is sharded across the whole mesh (each GPU holds 1/8 of the model)
+# GPUs 0,1 = batch 0
+# GPUs 2,3 = batch 1
+... and so on.
+```
+
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/deferring_execution.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/deferring_execution.md
new file mode 100644
index 0000000000000000000000000000000000000000..e90f889256fcae0bf09798200fce1929ca8df027
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/deferring_execution.md
@@ -0,0 +1,130 @@
+
+
+# Executing and deferring jobs
+
+When you run your usual script, instructions are executed in order. Using Accelerate to deploy your script on several
+GPUs at the same time introduces a complication: while each process executes all instructions in order, some may be
+faster than others.
+
+You might need to wait for all processes to have reached a certain point before executing a given instruction. For
+instance, you shouldn't save a model before being sure every process is done with training, and you wouldn't want to
+continue training before all the model weights have been loaded in. To do this, just write the following line in your code:
+
+```
+accelerator.wait_for_everyone()
+```
+
+This instruction will block all the processes that arrive first until all the other processes have reached that
+point (if you run your script on just one GPU or CPU, this won't do anything).
+
+A few example cases of when to use this utility are listed below:
+
+
+
+ Some of these are utilized with the [`~Accelerator.main_process_first`] context manager, which utilizes [`~Accelerator.wait_for_everyone`] to
+ run a particular set of code on the main process beforehand before triggering and launching the other processes
+
+
+
+## Downloading a Dataset
+
+When downloading a dataset, you should download it first on the main process and then load the cached dataset afterward
+
+
+
+ `load_dataset` will perform a lock under the hood to stop multiple downloads from happening at once, but if you are downloading something
+ not using this library you should use this method.
+
+
+
+```python
+with accelerator.main_process_first():
+ datasets = load_dataset("glue", "mrpc")
+```
+
+Under the hood this is the same as calling:
+
+```python
+# First do something on the main process
+if accelerator.is_main_process:
+ datasets = load_dataset("glue", "mrpc")
+else:
+ accelerator.wait_for_everyone()
+
+# And then send it to the rest of them
+if not accelerator.is_main_process:
+ datasets = load_dataset("glue", "mrpc")
+else:
+ accelerator.wait_for_everyone()
+```
+
+## Saving the `state_dict`
+
+When saving the `state_dict` of the model, since you would normally save one file on just the main process
+you should specify that:
+
+```python
+if accelerator.is_main_process:
+ model = accelerator.unwrap_model(model)
+ torch.save(model.state_dict(), "weights.pth")
+```
+
+## Loading in the `state_dict`
+
+When loading in the `state_dict` to a model, optimizer, or scheduler, you should wait
+for all workers to have the weights loaded in before moving on to training
+
+```python
+with accelerator.main_process_first():
+ state = torch.load("weights.pth")
+ model.load_state_dict(state)
+```
+
+## Applying a multi-worker CPU operation
+
+Applying a `map()` operation on multiple workers, such as tokenizing should be done on the
+main process first, and then propagated to each one.
+
+```python
+datasets = load_dataset("glue", "mrpc")
+
+with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+```
+
+## Applying checks such as Early Stopping
+
+To have a check that works with a flag set by a particular process, the `set_trigger` and `check_trigger` API should be used. Useful examples
+for doing so can include situations such as using early stopping and monitoring the loss (as each loss slightly differs on each process).
+
+Call [`Accelerator.set_trigger`] when your condition has been met, and [`Accelerator.check_trigger`] when checking if that condition has been met in any process:
+
+```python
+for (x,y) in data_loader:
+ logits = model(x)
+ loss = loss_func(logits, y)
+ # Assume `should_do_early_stopping` is a custom defined function that returns a conditional
+ if should_do_early_stopping(loss):
+ accelerator.set_trigger()
+
+ # Later in the training script when we need to check for the breakpoint
+ if accelerator.check_trigger():
+ break
+```
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/fsdp1_vs_fsdp2.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/fsdp1_vs_fsdp2.md
new file mode 100644
index 0000000000000000000000000000000000000000..f338ab638849b013d4b3f854b8241987b940a18d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/fsdp1_vs_fsdp2.md
@@ -0,0 +1,105 @@
+
+
+# FSDP1 vs FSDP2
+
+This guide explains the key differences between `FSDP1` and `FSDP2` and helps you migrate your existing code to use `FSDP2` with minimal changes.
+
+## How is FSDP2 better than FSDP1?
+
+First, we want to understand how `FSDP1` and `FSDP2` work internally to understand the differences between them. This also helps us understand the limitations of `FSDP1` and how `FSDP2` solves them.
+
+We'll be discussing a scenario where we have a single `Layer` that contains 3 `Linear` layers and is wrapped using `FSDP` to be sharded across 2 GPUs.
+
+
+
+
+
+### FSDP1
+First, we have to understand the original `FSDP1` and the limitations it brings. It represents each `FSDP` module as a single `FlatParameter` which is a single 1D tensor that contains all of the module parameters, which then get sharded across ranks. I.e. if you wrap the `Layer` with `FSDP1`, you'd achieve something as such:
+
+
+
+
+
+You might notice a problem. The whole `Layer` gets flattened into a single `FlatParameter`, which then gets sharded across ranks. But if it's a single `FlatParameter` object, how do we store metadata? That is one of the limitations. Properly storing per-parameter metadata such as `dtype`, `requires_grad`, etc. is not possible without some ugly hacks.
+
+### FSDP2
+This is why `FSDP2` was introduced. It doesn't use `FlatParameter`, instead it uses `DTensor` which is short for "Distributed Tensor". Each `DTensor` basically represents a vanilla `torch.Tensor` that has been sharded across ranks. It contains metadata about the original `torch.Tensor` and how it's sharded, what is the [placement type](https://pytorch.org/docs/stable/distributed.tensor.html#module-torch.distributed.tensor.placement_types) and so on. This is why it's called `per-parameter sharding`. The following figure shows the difference:
+
+
+
+
+
+Each Parameter of the original `Layer` is sharded across the 0th dimension, and split between 2 GPUs. Now, each `Linear` layer is a separate `DTensor` and storing metadata per-parameter is possible and straightforward.
+
+
+> [!TIP]
+> In the image above, the tensors were sharded across the 1st dimension for the sake of fitting the image on the screen, in reality, they are sharded across the 0th dimension as stated above
+
+## What does FSDP2 offer?
+
+`FSDP2` is a new and improved version of PyTorch's fully-sharded data parallel training API. Its main advantage is using `DTensor` to represent sharded parameters. Compared to `FSDP1`, it offers:
+- Simpler internal implementation, where each `Parameter` is a separate `DTensor`
+- Enables simple partial parameter freezing because of the above, which makes methods as [`LORA`](https://huggingface.co/papers/2106.09685) work out of the box
+- With `DTensor`, `FSDP2` supports mixing `fp8` and other parameter types in the same model out of the box
+- Faster and simpler checkpointing without extra communication across ranks using `SHARDED_STATE_DICT` and [`torch.distributed.checkpoint`](https://pytorch.org/docs/stable/distributed.checkpoint.html), this way, each rank only saves its own shard and corresponding metadata
+- For loading, it uses a `state_dict` of the sharded model to directly load the sharded parameters
+- Support for asynchronous checkpointing, where parameters are first copied to CPU memory, after this, main thread continues training while another thread stores the parameters on disk
+- Memory efficiency and deterministic memory usage, `FSDP2` doesn't use `recordStream` anymore and uses stream-to-stream synchronization (for more technical details see [this forum post](https://dev-discuss.pytorch.org/t/fsdp-cudacachingallocator-an-outsider-newb-perspective/1486) and [this issue](https://github.com/pytorch/pytorch/issues/114299))
+- In the future, optimizations of the communication patterns via `torch.compile` are planned, further improving the performance and memory efficiency
+
+
+## API Differences
+
+We have already discussed the internal differences, now let's discuss the differences, you, as a user, will need to know.
+
+Here are the main changes in configuration options when using `FSDP2` through the `accelerate` CLI:
+
+Previous (`FSDP1`) | New (`FSDP2`) | What Changed
+-- | -- | --
+`--fsdp_sharding_strategy` | `--fsdp_reshard_after_forward` | replaces `--fsdp_sharding_strategy`, changed to `true` (previously `FULL_SHARD`) or `false` (previously `SHARD_GRAD_OP`)
+`--fsdp_backward_prefetch` | \*\***REMOVED**\*\* | `FSDP2` uses previous `BACKWARD_PRE` option by default, as only this allows communication and computation overlap
+`--fsdp_forward_prefetch` | \*\***NOT YET IMPLEMENTED**\*\* | How to implement this is under active discussion, for now it is not supported in `FSDP2`
+`--fsdp_sync_module_states` | \*\***REMOVED**\*\* | with `FSDP2`, this parameter becomes redundant
+`--fsdp_cpu_ram_efficient_loading` | `--fsdp_cpu_ram_efficient_loading` | if `true`, `FSDP2` will similarly load the model only on rank 0, and then parameters get synced to other ranks, this is the same behavior as `FSDP1`, however, setting `--fsdp_sync_module_states` isn't required anymore
+`--fsdp_state_dict_type` | `--fsdp_state_dict_type` | `LOCAL_STATE_DICT` becomes obsolete and with `FSDP2` `SHARDED_STATE_DICT` is the default option, which results in no extra communication and each rank saving its own shard, other possible option is `FULL_STATE_DICT` which results in extra communication and spike in memory usage but saves the full model from rank 0.
+`--fsdp_use_orig_params` | \*\***REMOVED**\*\* | `FSDP2` uses a `DTensor` class on the background, which means it *always* uses the original parameters by default
+\*\***NEW**\*\* | `--fsdp_version` | `1` is the default option, to not break existing code, set to `2` to use `FSDP2`
+
+For all other options that remain unchanged, see the [`FSDP` documentation](../usage_guides/fsdp.md).
+
+## How to Switch to FSDP2
+
+### If using Python code:
+Simply set `fsdp_version=2` when creating your plugin and replace options according to the table above.
+
+```python
+from accelerate import FullyShardedDataParallelPlugin, Accelerator
+
+fsdp_plugin = FullyShardedDataParallelPlugin(
+ fsdp_version=2
+ # other options...
+)
+accelerator = Accelerator(fsdp_plugin=fsdp_plugin)
+```
+
+### If using YAML config:
+Use our conversion tool:
+```bash
+accelerate to-fsdp2 --config_file config.yaml --output_file new_config.yaml
+```
+
+This will automatically convert all FSDP1 settings to their FSDP2 equivalents. Use `--overwrite` to update the existing file instead of creating a new one.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/fsdp_and_deepspeed.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/fsdp_and_deepspeed.md
new file mode 100644
index 0000000000000000000000000000000000000000..c18daf52a8db860f478eb9adb3ad27aaa513964c
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/fsdp_and_deepspeed.md
@@ -0,0 +1,192 @@
+
+
+# FSDP vs DeepSpeed
+
+Accelerate offers flexibilty of training frameworks, by integrating two extremely powerful tools for distributed training, namely [Pytorch FSDP](../usage_guides/fsdp) and [Microsoft DeepSpeed](../usage_guides/deepspeed). The aim of this tutorial is to draw parallels, as well as to outline potential differences, to empower the user to switch seamlessly between these two frameworks.
+
+
+
+ To switch between the frameworks, we recommend launching code `accelerate launch` passing in the correct config file with `--config_file`, or passing in the respective arguments directly for [FSDP and DeepSpeed](../package_reference/cli#accelerate-launch) .
+
+ Example Accelerate configurations can be found here for [DeepSpeed](../usage_guides/deepspeed#accelerate-deepspeed-plugin) and [FSDP](../usage_guides/fsdp#how-it-works-out-of-the-box), or in the [example zoo under "Launch Configurations"](../usage_guides/explore)
+
+
+
+
+
+This tutorial is for single-node, multi-GPU, scenarios only.
+
+
+
+## Configuring Functionalities
+
+Model tensors are split into different GPUs in an attempt to scale up model sizes; this is termed *sharding* in FSDP, and *partitioning* in DeepSpeed. FSDP sharding and DeepSpeed ZeRO (partitioning) stages are configured by `--fsdp_sharding_strategy`, and `--zero_stage`, respectively. In particular, FSDP `FULL_SHARD` maps to DeepSpeed ZeRO stage `3`; see this [comprehensive mapping between FSDP sharding and DeepSpeed ZeRO settings](../usage_guides/fsdp#mapping-between-fsdp-sharding-strategies-and-deepspeed-zero-stages). The below table summarizes and groups similar settings:
+
+Group | Framework | Configuration | Example | Restrictions (if any)
+--|--|--|--|--
+sharding / partitioning | FSDP DeepSpeed | `--fsdp_sharding_strategy` `--zero_stage` | `1` (`FULL_SHARD`) `3` |
+offload | FSDP DeepSpeed | `--fsdp_offload_params` `--offload_param_device` `--offload_optimizer_device` | `true` `cpu` `cpu` | all or nothing
+model loading | FSDP DeepSpeed | `--fsdp_cpu_ram_efficient_loading` `--zero3_init_flag` | `true` `true` | only ZeRO 3
+efficient checkpointing | FSDP DeepSpeed | `--fsdp_state_dict_type` `--zero3_save_16bit_model` | `SHARDED_STATE_DICT` `true` | only ZeRO 3
+weights prefetching | FSDP
DeepSpeed | `--fsdp_auto_wrap_policy` `--fsdp_transformer_layer_cls_to_wrap` None | `TRANSFORMER_BASED_WRAP` | Usually not needed Transparent to user.
+parameters summoning | FSDP DeepSpeed | `--fsdp_use_orig_params` None | `true` | required for `torch.compile` Transparent to user
+parameters syncing | FSDP DeepSpeed | `--fsdp_sync_module_states` None | `true` |
+training | FSDP DeepSpeed | None `--gradient_accumulation_steps` `--gradient_clipping` | `auto` `auto` | Transparent to user
+
+For detailed descriptions of the above, refer to [`Accelerate` launch documentation](../package_reference/cli#accelerate-launch).
+
+
+
+ To access other DeepSpeed configurations, such as mixed precision settings,
+ you need to pass in a `--deepspeed_config_file`, see the [documentation](../usage_guides/deepspeed#deepspeed-config-file).
+
+ DeepSpeed can be also configured via [`DeepSpeedPlugin`], e.g., `DeepSpeedPlugin.zero_stage` is equivalent of `--zero_stage`, and `DeepSpeedPlugin.hf_ds_config` can be used to pass `--deepeed_config_file.`
+
+
+
+
+
+ FSDP can be also configured via [`FullyShardedDataParallelPlugin`], e.g., `FullyShardedDataParallelPlugin.sharding_strategy` is equivalent of `--fsdp_sharding_strategy`.
+
+
+
+### Checkpointing
+
+Do note that while FSDP can be configured via `--fsdp_state_dict_type` to save either full / sharded checkpoints.
+
+
+
+ For DeepSpeed Zero3, one could pass a `--zero3_save_16bit_model true`, which conveniently consolidates the model to a single rank and saves; this is the FSDP equivalent of `fsdp_state_dict_type: FULL_STATE_DICT`.
+
+
+
+
+
+ For large models, consolidating the model to a single rank can be very slow.
+
+
+
+
+
+ For quicker checkpointing, for FSDP use `fsdp_state_dict_type: SHARDED_STATE_DICT`, and for DeepSpeed Zero3 [use the `zero_to_fp32.py` script to post-convert sharded checkpoints](https://www.deepspeed.ai/tutorials/zero/#extracting-weights).
+
+
+
+
+### Offloading
+
+FSDP only allows *all-or-nothing* offload (i.e., either offload parameters, gradients, and optimizer, or keep them all in GPU), but DeepSpeed can offload parameters and optimizer differently. Furthermore, DeepSpeed also supports [offloading to NVME](https://www.deepspeed.ai/docs/config-json/#parameter-offloading).
+
+### Prefetching
+
+FSDP allows two prefetching configurations `--fsdp_forward_prefetch` and `--fsdp_backward_prefetch` to improve overlap of comms / computation at a cost of extra memory, see [FSDP documentation](https://pytorch.org/docs/stable/fsdp.html).
+For DeepSpeed, the prefetching will be turned on when needed, and it turns on depending on certain hyper-params like `stage3_param_persistence_threshold`, `stage3_max_reuse_distance`, etc, [that can be configured for Zero3](https://www.deepspeed.ai/docs/config-json/#parameter-offloading); `accelerate` may set these hyper-params automatically if you don't set those explicitly in the deepspeed config file.
+
+
+
+ For FSDP set `fsdp_backward_prefetch: BACKWARD_PRE` for improved throughputs if memory allows.
+
+
+
+### Model Loading
+
+While FSDP require an explicit `--fsdp_cpu_ram_efficient_loading true` to activate efficient model loading, `transformers` will activate the similar feature whenever DeepSpeed Zero3 is used.
+
+
+
+ For FSDP, whenever setting `--fsdp_cpu_ram_efficient_loading true`, `accelerate` will automatically set `sync_module_states` to true.
+ For RAM efficient loading the weights will be loaded only in a single rank, and thus requires `sync_module_states` to broadcast weights to other ranks.
+
+
+
+### Model
+
+FSDP requires an explicit `--fsdp_auto_wrap_policy` for the algorithm to decide how to schedule the all-gather and reduce-scatter operations. But for DeepSpeed this is transparent to the user.
+
+
+
+ For FSDP, simply set `fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP`. With the latest [`transformers`] versions, we try our best to figure out the suitable `fsdp_transformer_layer_cls_to_wrap` for HF transformers models. However, if you get an error regarding it, please specify this.
+
+
+
+### Parameters Summoning
+
+FSDP requires an explicit `--fsdp_use_orig_params` flag if using `torch.compile`, see [the pytorch documentation](https://pytorch.org/docs/stable/fsdp.html#module-torch.distributed.fsdp). For DeepSpeed this is transparent to the user.
+
+
+
+ For FSDP, when using `torch.compile` please set `fsdp_use_orig_params: True`.
+
+
+
+
+## Training
+
+Deepspeed requires explicit `--gradient_accumulation_steps` and `--gradient_clipping` flags. For FSDP this is transparent to the user.
+
+
+
+ When using DeepSpeed, set `gradient_accumulation_steps: "auto"` and `gradient_clipping: "auto"` to automatically pick up values set in the [`Accelerator`] or [`TrainingArguments`] (if using `transformers`).
+
+
+
+
+## On Differences in Data Precision Handling
+
+To discuss how data precision is handled in both FSDP and Deepspeed, it is instructive to first give an overview of how model parameters are handled in these frameworks. Before the model / optimizer parameters are distributed across GPUs, parameter preparation is involved to first "flatten" them to one-dimensional [`torch.Tensor`](https://pytorch.org/docs/stable/tensors.html#torch-tensor). The implementation of FSDP / DeepSpeed varies in the respect of the `dtype` in which these "flattened" parameters are stored, and there are ramifications with regards to how [`torch.Optimizer`](https://pytorch.org/docs/stable/optim.html#module-torch.optim) allocate their `dtype`s. The table below outlines the processes for both frameworks; the "Local" column indicates the process occurring at a per-gpu level, therefore any memory overheads by upcasting should be understood to be amortized by the number of gpus used.
+
+
+
+ As a rule of thumb, for stable training with automatic mixed precision, all the trainable parameters have to be in `torch.float32`.
+
+
+
+Process | Local | Framework | Details
+--|--|--|--
+Loading, i.e., [`AutoModel.from_pretrained(..., torch_dtype=torch_dtype)`] |
+Preparation, i.e., creation of "flat params" | ✅ | FSDP DeepSpeed | created in `torch_dtype`. disregards `torch_dtype`, created in `float32`.
+Optimizer initialization | ✅ | FSDP DeepSpeed | creates parameters in `torch_dtype` creates parameters in `float32`
+Training Step, i.e, forward, backward, reduction | | FSDP DeepSpeed | follows [`MixedPrecision`](https://pytorch.org/docs/stable/fsdp.html#torch.distributed.fsdp.MixedPrecision) follows `deepspeed_config_file` mixed precision settings.
+Optimizer (Pre-Step) | ✅ | FSDP DeepSpeed | upcasting (if any) to `torch_dtype` upcasted to `float32`
+Optimizer (Actual Step) | ✅ | FSDP DeepSpeed | occurs in `torch_dtype` occurs in `float32`.
+
+
+
+ Therefore when using DeepSpeed a small number of GPUs, be aware of potentially significant memory overheads due to the upcasting during preparation.
+
+
+
+
+
+ With FSDP, in the absence of mixed precision, it is possible to operate the [`torch.Optimizer`](https://pytorch.org/docs/stable/optim.html#module-torch.optim) in low precision `torch_dtype`, which may be helpful when using small number of GPUs.
+
+
+
+
+
+ With mixed precision, FSDP and DeepSpeed will upcast in the model preparation step (c.f. table above). But do note that FSDP will then save checkpoints in the upcasted precision; Deepspeed may still save low precision checkpoints if `--zero3_save_16bit_model` is specified.
+
+
+
+
+To clarify the above table consider the concrete examples below; the optimizer pre- and actual step combined for brevity. With FSDP it is possible to operate in the two modes shown below, but DeepSpeed can only operate in one.
+
+Framework | Model Loading (`torch_dtype`) | Mixed Precision | Preparation (Local) | Training | Optimizer (Local)
+--|--|--|--|--|--
+FSDP | bf16 | default (none) | bf16 | bf16 | bf16
+FSDP | bf16 | bf16 | fp32 | bf16 | fp32
+DeepSpeed | bf16 | bf16 | fp32 | bf16 | fp32
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/gradient_synchronization.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/gradient_synchronization.md
new file mode 100644
index 0000000000000000000000000000000000000000..523f6a916acba36c1e91c14fa4446ea1799ccfd2
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/gradient_synchronization.md
@@ -0,0 +1,184 @@
+
+
+# Gradient synchronization
+
+PyTorch's distributed module operates by communicating back and forth between all of the GPUs in your system.
+This communication takes time, and ensuring all processes know the states of each other happens at particular triggerpoints
+when using the `ddp` module.
+
+These triggerpoints are added to the PyTorch model, specifically their `forward()` and `backward()` methods.
+This happens when the model is wrapped with `DistributedDataParallel`:
+```python
+import torch.nn as nn
+from torch.nn.parallel import DistributedDataParallel
+
+model = nn.Linear(10, 10)
+ddp_model = DistributedDataParallel(model)
+```
+In Accelerate this conversion happens automatically when calling [`~Accelerator.prepare`] and passing in your model.
+
+```diff
++ from accelerate import Accelerator
++ accelerator = Accelerator()
+ import torch.nn as nn
+- from torch.nn.parallel import DistributedDataParallel
+
+ model = nn.Linear(10,10)
++ model = accelerator.prepare(model)
+```
+
+## The slowdown in gradient accumulation
+
+You now understand that PyTorch adds hooks to the `forward` and `backward` method of your PyTorch model when
+training in a distributed setup. But how does this risk slowing down your code?
+
+In DDP (distributed data parallel), the specific order in which processes are performed and ran are expected
+at specific points and these must also occur at roughly the same time before moving on.
+
+The most direct example is when you update model parameters through
+`optimizer.step()`.
+Without gradient accumulation, all instances of the model need to have updated
+their gradients computed, collated, and updated before moving on to the next
+batch of data.
+When performing gradient accumulation, you accumulate `n` loss gradients and
+skip `optimizer.step()` until `n` batches have been reached. As all training
+processes only need to synchronize by the time `optimizer.step()` is called,
+without any modification to your training step, this needless inter-process
+communication can cause a significant slowdown.
+
+ How can you avoid this overhead?
+
+## Solving the slowdown problem
+
+Since you are skipping model parameter updates when training on these batches, their gradients do not need to be synchronized until the point where `optimizer.step()` is actually called.
+PyTorch cannot automagically tell when you need to do this, but they do provide a tool to help through the [`no_sync`](https://pytorch.org/docs/stable/generated/torch.nn.parallel.DistributedDataParallel.html#torch.nn.parallel.DistributedDataParallel.no_sync) context manager
+that is added to your model after converting it to DDP.
+
+Under this context manager, PyTorch will skip synchronizing the gradients when
+`.backward()` is called, and the first call to `.backward()` outside this
+context manager will trigger the synchronization. See an example below:
+```python
+ddp_model, dataloader, optimizer = accelerator.prepare(model, dataloader, optimizer)
+
+for index, batch in enumerate(dataloader):
+ inputs, targets = batch
+ # Trigger gradient synchronization on the last batch
+ if index != (len(dataloader) - 1):
+ with ddp_model.no_sync():
+ # Gradients only accumulate
+ outputs = ddp_model(inputs)
+ loss = loss_func(outputs)
+ accelerator.backward(loss)
+ else:
+ # Gradients finally sync
+ outputs = ddp_model(inputs)
+ loss = loss_func(outputs)
+ accelerator.backward(loss)
+ optimizer.step()
+```
+
+In Accelerate to make this an API that can be called no matter the training device (though it may not do anything if you are not in a distributed system!),
+`ddp_model.no_sync` gets replaced with [`~Accelerator.no_sync`] and operates the same way:
+
+```diff
+ ddp_model, dataloader, optimizer = accelerator.prepare(model, dataloader, optimizer)
+
+ for index, batch in enumerate(dataloader):
+ inputs, targets = batch
+ # Trigger gradient synchronization on the last batch
+ if index != (len(dataloader)-1):
+- with ddp_model.no_sync():
++ with accelerator.no_sync(model):
+ # Gradients only accumulate
+ outputs = ddp_model(inputs)
+ loss = loss_func(outputs, targets)
+ accelerator.backward(loss)
+ else:
+ # Gradients finally sync
+ outputs = ddp_model(inputs)
+ loss = loss_func(outputs)
+ accelerator.backward(loss)
+ optimizer.step()
+ optimizer.zero_grad()
+```
+
+As you may expect, the [`~Accelerator.accumulate`] function wraps around this conditional check by keeping track of the current batch number, leaving you with the final
+gradient accumulation API:
+
+```python
+ddp_model, dataloader, optimizer = accelerator.prepare(model, dataloader, optimizer)
+
+for batch in dataloader:
+ with accelerator.accumulate(model):
+ optimizer.zero_grad()
+ inputs, targets = batch
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets)
+ accelerator.backward(loss)
+ optimizer.step()
+ optimizer.zero_grad()
+```
+
+As a result, you should either use *`accelerator.accumulate` or `accelerator.no_sync`* when it comes to API choice.
+
+## Just how much of a slowdown is there, and easy mistakes you can make
+
+To set up a realistic example, consider the following setup:
+
+* Two single-GPU T4 nodes and one node with two GPUs
+* Each GPU is a T4, and are hosted on GCP
+* The script used is a modification of the [NLP Example](https://github.com/muellerzr/timing_experiments/blob/main/baseline.py) script
+* Batch size per GPU is 16, and gradients are accumulated every 4 steps
+
+All scripts are available in [this repository](https://github.com/muellerzr/timing_experiments).
+
+If not careful about gradient synchronization and GPU communication, a *large* amount of time can be wasted
+from when these GPUs communicate to each other during unnecessary periods.
+
+By how much?
+
+Reference:
+- Baseline: uses no synchronization practices discussed here
+- `no_sync` improperly: `no_sync` only around the `backward` call, not the `forward`
+- `no_sync`: using the `no_sync` pattern properly
+- `accumulate`: using [`~Accelerator.accumulate`] properly
+
+Below are the average seconds per batch iterating over 29 batches of data for each setup on both a single node and on the dual-node setup:
+
+| | Baseline | `no_sync` improperly | `no_sync` | `accumulate`|
+| :---------: | :-------: | :------------------: | :-------: | :---------: |
+| Multi-Node | 2±0.01s | 2.13±0.08s | **0.91±0.11s** | **0.91±0.11s** |
+| Single Node | 0.50±0.01s | 0.50±0.01s | **0.41±0.015s** | **0.41±0.015s** |
+
+As you can see, if you are not careful about how you set up your gradient synchronization, you can get upwards of more than a 2x slowdown during training!
+
+If you are worried about making sure everything is done properly, we highly recommend utilizing the [`~Accelerator.accumulate`] function and passing in
+`gradient_accumulation_steps` or `gradient_accumulation_plugin` to the [`Accelerator`] object so Accelerate can handle this for you.
+
+### `no_sync` requires additional GPU memory when using FSDP
+
+Be aware that not syncing gradients can have adverse effects while performing FSDP training. As it has been warned in `torch`, the [`no_sync` context manager for FSDP](https://pytorch.org/docs/stable/fsdp.html#torch.distributed.fsdp.FullyShardedDataParallel.no_sync) will require additional memory.
+
+Therefore in memory intensive situations while using FSDP, we recommend to set `sync_each_batch` to `True` in the [`~utils.GradientAccumulationPlugin`] to disable `no_sync`.
+
+See the example below where we fine-tune Mixtral (47B parameters) on 8 A100-80GB GPUs. We see that even for a modest `gradient_accumulation_steps=2` we quickly go out-of-memory (OOM) if `no_sync` is enabled. Again, this is due to additional memory overheads due to FSDP's `no_sync`. However, if `no_sync` is disabled via `sync_each_batch=True`, then the memory consumption for `gradient_accumulation_steps=16` reverts to that of `gradient_accumulation_steps=1`.
+
+| Model | `no_sync` (accum=1) | `no_sync` (accum=2) | `no_sync` disabled (accum=16)
+| :-------------: | :-----------------: | :-----------------: | :-----------------:
+mixtral 8x7B | 69G | OOM | 69G
+
+> [!WARNING]
+> Disabling `no_sync` means there _will be slowdown_ due the extra data syncs, as explained by the earlier sections of this guide.
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/internal_mechanism.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/internal_mechanism.md
new file mode 100644
index 0000000000000000000000000000000000000000..5f41c02bce5025943d3ae06128f79b31e6323600
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/internal_mechanism.md
@@ -0,0 +1,74 @@
+
+
+# Accelerate's internal mechanisms
+
+Internally, Accelerate works by first analyzing the environment in which the script is launched to determine which
+kind of distributed setup is used, how many different processes there are and which one the current script is in. All
+that information is stored in the [`~AcceleratorState`].
+
+This class is initialized the first time you instantiate an [`~Accelerator`] as well as performing any
+specific initialization your distributed setup needs. Its state is then uniquely shared through all instances of
+[`~state.AcceleratorState`]. (The same can also be done with the [`PartialState`], a more barebones version it inherits)
+
+Then, when calling [`~Accelerator.prepare`], the library:
+
+- wraps your model(s) in the container adapted for the distributed setup,
+- wraps your optimizer(s) in an [`~optimizer.AcceleratedOptimizer`],
+- wraps your scheduler(s) in an [`~scheduler.AcceleratedScheduler`]
+- creates a new version of your dataloader(s) in a [`~data_loader.DataLoaderShard`] or [`~data_loader.DataLoaderDispatcher`]
+
+While the model(s), optimizer(s), and scheduler(s) are just put in simple wrappers, the dataloader(s) are re-created. This is mostly
+because PyTorch does not let the user change the `batch_sampler` of a dataloader once it's been created and the
+library handles the sharding of your data between processes by changing that `batch_sampler` to yield every other
+`num_processes` batches (if enabled).
+
+The [`~data_loader.DataLoaderShard`] subclasses `DataLoader` to add the following functionality:
+
+- it synchronizes the appropriate random number generator of all processes at each new iteration, to ensure any
+ randomization (like shuffling) is done the exact same way across processes.
+- it puts the batches on the proper device before yielding them (unless you have opted out of
+ `device_placement=True`).
+
+The [`~data_loader.DataLoaderDispatcher`] subclasses differs from the [`~data_loader.DataLoaderShard`] in that when iterating through the `DataLoader`, the data is all starting from process 0 and *then* split and sent off to each process rather than it happening at the dataset level.
+
+The random number generator synchronization will by default synchronize:
+
+- the `generator` attribute of a given sampler (like the PyTorch `RandomSampler`) for PyTorch >= 1.6
+- the main random number generator in PyTorch <=1.5.1
+
+You can choose which random number generator(s) to synchronize with the `rng_types` argument of the main
+[`Accelerator`]. In PyTorch >= 1.6, it is recommended to rely on a local `generator` to avoid
+setting the same seed in the main random number generator in all processes.
+
+
+
+ Synchronization of the main torch (or CUDA or XLA) random number generator will affect any other potential random
+ artifacts you could have in your dataset (like random data augmentation) in the sense that all processes will get
+ the same random numbers from the torch random modules (so will apply the same random data augmentation if it's
+ controlled by torch).
+
+
+
+
+
+ The randomization part of your custom sampler, batch sampler or iterable dataset should be done using a local
+ `torch.Generator` object (in PyTorch >= 1.6), see the traditional `RandomSampler`, as an example.
+
+
+
+If you have [`torchdata>=0.8.0`](https://github.com/pytorch/data/tree/main) installed, and you have passed `use_stateful_dataloader=True` into your [`~utils.DataLoaderConfiguration`], these classes will directly inherit from `StatefulDataLoader` instead, and maintain a `state_dict`.
+
+For more details about the internals, see the [Internals page](../package_reference/torch_wrappers).
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/low_precision_training.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/low_precision_training.md
new file mode 100644
index 0000000000000000000000000000000000000000..e7527cce758b3564f36c2e7b8c8c8e44d14ccee1
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/low_precision_training.md
@@ -0,0 +1,74 @@
+
+
+# Low precision training methods
+
+The release of new kinds of hardware led to the emergence of new training paradigms that better utilize them. Currently, this is in the form of training
+in 8-bit precision using packages such as [TransformersEngine](https://github.com/NVIDIA/TransformerEngine) (TE) or [MS-AMP](https://github.com/Azure/MS-AMP/tree/main).
+
+For an introduction to the topics discussed today, we recommend reviewing the [low-precision usage guide](../usage_guides/low_precision_training) as this documentation will reference it regularly.
+
+## A Quick Chart
+
+Below is a quick chart from the MS-AMP documentation showing the different bit-precisions for each solution during training:
+
+Optimization Level | Computation(GEMM) | Comm | Weight | Master Weight | Weight Gradient | Optimizer States
+-- | -- | -- | -- | -- | -- | --
+FP16 AMP | FP16 | FP32 | FP32 | N/A | FP32 | FP32+FP32
+Nvidia TE | FP8 | FP32 | FP32 | N/A | FP32 | FP32+FP32
+MS-AMP O1 | FP8 | FP8 | FP16 | N/A | FP8 | FP32+FP32
+MS-AMP O2 | FP8 | FP8 | FP16 | N/A | FP8 | FP8+FP16
+MS-AMP O3 | FP8 | FP8 | FP8 | FP16 | FP8 | FP8+FP16
+
+## `TransformersEngine`
+
+`TransformersEngine` is the first solution to trying to train in 8-bit floating point. It works by using drop-in replacement layers for certain ones in a model that utilizes their FP8-engine to reduce the number of bits (such as 32 to 8) without degrading the final accuracy of the model.
+
+Specifically, Accelerate will find and replace the following layers with `TransformersEngine` versions:
+
+* `nn.LayerNorm` for `te.LayerNorm`
+* `nn.Linear` for `te.Linear`
+
+As a result we wind up with a model that has most of its layers in BF16, while some layers are in FP8 reducing some of the memory.
+
+Anecdotally, we have noticed that performance gains don't really start showing when using `TransformerEngine` until a large majority of the layers
+in the model are made up of those two layers to replace. As a result, only larger models have shown performance improvements when the number of parameters is around and upwards of a few billion.
+
+The `TransformerEngine` can receive many different arguments that customize how it performs FP8 calculations and what they do. A full list of the arguments is available below:
+
+* `margin`: The margin to use for the gradient scaling.
+* `interval`: The interval to use for how often the scaling factor is recomputed.
+* `fp8_format``: The format to use for the FP8 recipe. Must be one of `HYBRID` or `E4M3`. (Generally `HYBRID` for training, `E4M3` for evaluation)
+* `amax_history_len`: The length of the history to use for the scaling factor computation
+* `amax_compute_algo`: The algorithm to use for the scaling factor computation. Must be one of `max` or `most_recent`.
+* `override_linear_precision`: Whether or not to execute `fprop`, `dgrad`, and `wgrad` GEMMS in higher precision.
+
+You can customize each of these as part of [`utils.FP8RecipeKwargs`] to help optimize performance of your models.
+
+If we notice in the chart mentioned earlier, TE simply casts the computation layers into FP8, while everything else is in FP32. As a result this winds up utilizing the most memory but does so with the benefit of guaranteeing the least amount of loss in end accuracy during training.
+
+## `MS-AMP`
+
+MS-AMP takes a different approach to `TransformersEngine` by providing three different optimization levels to convert more operations in FP8 or FP16.
+
+* The base optimization level (`O1`), passes communications of the weights (such as in DDP) in FP8, stores the weights of the model in FP16, and leaves the optimizer states in FP32. The main benefit of this optimization level is that we can reduce the communication bandwidth by essentially half. Additionally, more GPU memory is saved due to 1/2 of everything being cast in FP8, and the weights being cast to FP16. Notably, both the optimizer states remain in FP32.
+
+* The second optimization level (`O2`) improves upon this by also reducing the precision of the optimizer states. One is in FP8 while the other is in FP16. Generally it's been shown that this will only provide a net-gain of no degraded end accuracy, increased training speed, and reduced memory as now every state is either in FP16 or FP8.
+
+* Finally, MS-AMP has a third optimization level (`O3`) which helps during DDP scenarios such as DeepSpeed. The weights of the model in memory are fully cast to FP8, and the master weights are now stored in FP16. This fully reduces memory by the highest factor as now not only is almost everything in FP8, only two states are left in FP16. Currently, only DeepSpeed versions up through 0.9.2 are supported, so this capability is not included in the Accelerate integration
+
+## Combining the two
+
+More experiments need to be performed but it's been noted that combining both MS-AMP and TransformersEngine can lead to the highest throughput by relying on NVIDIA's optimized FP8 operators and utilizing how MS-AMP reduces the memory overhead.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/performance.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/performance.md
new file mode 100644
index 0000000000000000000000000000000000000000..6e444fa17c47cf7192386c57b6f7ae89b0967c60
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/performance.md
@@ -0,0 +1,103 @@
+
+
+# Comparing performance across distributed setups
+
+Evaluating and comparing the performance from different setups can be quite tricky if you don't know what to look for.
+For example, you cannot run the same script with the same batch size across TPU, multi-GPU, and single-GPU with Accelerate
+and expect your results to line up.
+
+But why?
+
+There are three reasons for this that this tutorial will cover:
+
+1. **Setting the right seeds**
+2. **Observed Batch Sizes**
+3. **Learning Rates**
+
+## Setting the Seed
+
+While this issue has not come up as much, make sure to use [`utils.set_seed`] to fully set the seed in all distributed cases so training will be reproducible:
+
+```python
+from accelerate.utils import set_seed
+
+set_seed(42)
+```
+
+Why is this important? Under the hood this will set **5** different seed settings:
+
+```python
+ random.seed(seed)
+ np.random.seed(seed)
+ torch.manual_seed(seed)
+ torch.cuda.manual_seed_all(seed) # or torch.xpu.manual_seed_all, etc
+ # ^^ safe to call this function even if cuda is not available
+ if is_torch_xla_available():
+ xm.set_rng_state(seed)
+```
+
+The random state, numpy's state, torch, torch's device state, and if TPUs are available torch_xla's cuda state.
+
+## Observed Batch Sizes
+
+When training with Accelerate, the batch size passed to the dataloader is the **batch size per GPU**. What this entails is
+a batch size of 64 on two GPUs is truly a batch size of 128. As a result, when testing on a single GPU this needs to be accounted for,
+as well as similarly for TPUs.
+
+The below table can be used as a quick reference to try out different batch sizes:
+
+
+
+In this example, there are two GPUs for "Multi-GPU" and a TPU pod with 8 workers
+
+
+
+| Single GPU Batch Size | Multi-GPU Equivalent Batch Size | TPU Equivalent Batch Size |
+|-----------------------|---------------------------------|---------------------------|
+| 256 | 128 | 32 |
+| 128 | 64 | 16 |
+| 64 | 32 | 8 |
+| 32 | 16 | 4 |
+
+## Learning Rates
+
+As noted in multiple sources[[1](https://aws.amazon.com/blogs/machine-learning/scalable-multi-node-deep-learning-training-using-gpus-in-the-aws-cloud/)][[2](https://docs.nvidia.com/clara/clara-train-sdk/pt/model.html#classification-models-multi-gpu-training)], the learning rate should be scaled *linearly* based on the number of devices present. The below
+snippet shows doing so with Accelerate:
+
+
+
+Since users can have their own learning rate schedulers defined, we leave this up to the user to decide if they wish to scale their
+learning rate or not.
+
+
+
+```python
+learning_rate = 1e-3
+accelerator = Accelerator()
+learning_rate *= accelerator.num_processes
+
+optimizer = AdamW(params=model.parameters(), lr=learning_rate)
+```
+
+You will also find that `accelerate` will step the learning rate based on the number of processes being trained on. This is because
+of the observed batch size noted earlier. So in the case of 2 GPUs, the learning rate will be stepped twice as often as a single GPU
+to account for the batch size being twice as large (if no changes to the batch size on the single GPU instance are made).
+
+## Gradient Accumulation and Mixed Precision
+
+When using gradient accumulation and mixed precision, due to how gradient averaging works (accumulation) and the precision loss (mixed precision),
+some degradation in performance is expected. This will be explicitly seen when comparing the batch-wise loss between different compute
+setups. However, the overall loss, metric, and general performance at the end of training should be _roughly_ the same.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/sequence_parallelism.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/sequence_parallelism.md
new file mode 100644
index 0000000000000000000000000000000000000000..9eb7262f38c29df3782e4050885d4aaa57ae99b4
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/sequence_parallelism.md
@@ -0,0 +1,219 @@
+
+
+# Sequence parallel in 🤗`accelerate`
+
+This guide will cover basics of using sequence parallelism in 🤗`accelerate`.
+
+See also the very related [Context Parallellism](./context_parallelism.md).
+
+## Why sequence parallelism?
+
+With the advent of large language models, and recently reasoning models, the sequence length has been growing rapidly. This, combined with quadratic memory complexity of attention, has led to a need for more efficient ways to train models with long sequences.
+With sequence length of 128k, the memory requirement of the attention matrix is `128k * 128k * 2 bytes * num_heads = ~32 GB * num_heads` for `bf16` precision, given vanilla attention implementation. Granted, with usage of `flash attention` or `SDPA` which do not materialize these attention weights, this decreases drastically, but the growth in memory requirements is still considerable.
+
+Ulysses Sequence parallelism allows us to shard the inputs to the attention computation along the sequence dimension and compute the attention normally, but using only a slice of attention heads on each GPU. With this, we can train models with long sequences, with a few more tools, scaling to 15M+ sequence length. To see how to augment Ulysses SP with TiledMLP, Liger-Kernel, Activation checkpoint offload to cpu and a few other tricks pleae refer to the paper: [Arctic Long Sequence Training: Scalable And Efficient Training For Multi-Million Token Sequences](https://arxiv.org/abs/2506.13996).
+
+## How is Ulysses SP different from FSDP CP
+
+In the document [Context Parallellism](./context_parallelism.md) you can learn about deploying another technology called Context Parallelism, which too slices on the sequence dimension but uses Ring Attention instead of slicing on the head dimension.
+
+The following articles go into a very detailed explanation of the differences between the two technologies:
+- https://insujang.github.io/2024-01-11/tensor-parallelism-and-sequence-parallelism-detailed-analysis/
+- https://huggingface.co/blog/exploding-gradients/ulysses-ring-attention
+
+A quick summary adapting from one of the articles:
+- Ulysses SP has a relatively low communication overhead, but is limited by the number of Attention Heads and thus it has certain requirements for network topology (number of attention heads has has to be divisible by the number of participating gpus for a single replica). All-to-all communication is sensitive to latency and it requires Deepspeed.
+- FSDP CP Ring-Attention's P2P ring communication has no aforementioned divisibilty requirements, but has a higher communication volume.
+
+Finally it should be possible to combine SP + CP as explained in the paper [USP: A Unified Sequence Parallelism Approach for Long Context Generative AI](https://arxiv.org/abs/2405.07719) to support an even longer sequence length, albeit this is not yet integrated into 🤗`accelerate`.
+
+
+## Supported sequence parallelism backends
+
+Currently the only sequence parallelism backend is `deepspeed`, which comes from the modernized Ulysses SP which is part of the [Arctic Long Sequence Training technology](https://arxiv.org/abs/2506.13996). There is also a [tutorial](https://www.deepspeed.ai/tutorials/ulysses-alst-sequence-parallelism/) should you want to integrate it into your own code directly.
+
+## How to use sequence parallelism?
+
+```diff
+from accelerate.utils import ParallelismConfig, DeepSpeedSequenceParallelConfig
+
++# Example: 4 GPUs with sp_size=4, dp_shard_size=1
++# Ensure: dp_replicate_size × dp_shard_size × sp_size = 1 × 1 × 4 = 4 GPUs
+parallelism_config = ParallelismConfig(
++ sp_backend="deepspeed",
++ sp_size=4,
++ dp_shard_size=1, # Explicit: no data parallelism
++ sp_handler=DeepSpeedSequenceParallelConfig(
++ sp_seq_length_is_variable: true,
++ sp_attn_implementation="sdpa",
++ ),
++ )
+
+accelerator = Accelerator(
+ ...,
+ parallelism_config=parallelism_config,
+)
+```
+
+As with any other feature in 🤗`accelerate`, you can enable sequence parallelism also by passing the corresponding flags to `accelerate launch`. In this case, it's no different:
+
+```bash
+accelerate launch --parallelism-config-sp-size 8 ...
+```
+
+> [!Tip]
+> You can also set the `sp_size` and other configuration in the `accelerate config` command, which will save them in your `accelerate` configuration file, so you don't have to pass them every time you launch your script.
+
+> [!Tip]
+> sequence parallelism combines with data parallelism. It doesn't require additional GPUs.
+> So if you have 8 gpus you can do: `--parallelism-config-dp-shard-size 8 --parallelism-config-sp-size 8`. Or you can use the `ParallelismConfig` class to set them programmatically.
+>
+> **Important**: You must ensure `dp_replicate_size × dp_shard_size × sp_size = num_processes`. For example, with 8 GPUs and `sp_size=8`, you need `dp_shard_size=1` (since 1 × 1 × 8 = 8). With 4 GPUs and `sp_size=2`, you could use `dp_shard_size=2` (since 1 × 2 × 2 = 4) for 2D parallelism.
+
+
+## ALST/Ulysses SP backend configuration
+
+ALST/UlyssesSP implements sequence parallelism using attention head parallelism, as explained in [this paper](https://arxiv.org/abs/2506.13996). For simplicity, we reuse the concept and setup of sequence parallelism, which, from the user's perspective, is the same: multiple GPUs are used to process a single batch.
+
+To give a sense of what ALST made possible - it allowed us to train in bf16 with 500K tokens on a single H100 GPU, 3.7M on a single node, and 15M on Llama-8B using just four nodes. This feature of HF Accelerate enables only 1 of the 3 ALST components, so the achievable sequence length will be smaller. You'd want TiledMLP, Activation checkpoint offload to CPU, and a few other things enabled to get the full power of ALST. For details, please refer to [this tutorial](https://www.deepspeed.ai/tutorials/ulysses-alst-sequence-parallelism/).
+
+To configure the `deepspeed` backend:
+
+```python
+# Example: 4 GPUs with sp_size=4, dp_shard_size=1
+# Ensure: dp_replicate_size × dp_shard_size × sp_size = 1 × 1 × 4 = 4 GPUs
+parallelism_config = ParallelismConfig(
+ sp_backend="deepspeed",
+ sp_size=4,
+ dp_shard_size=1, # Explicit: no data parallelism
+ sp_handler=DeepSpeedSequenceParallelConfig(
+ sp_seq_length=256,
+ sp_seq_length_is_variable=True,
+ sp_attn_implementation="sdpa",
+ ),
+)
+accelerator = Accelerator(
+ ...,
+ parallelism_config=parallelism_config,
+)
+```
+
+- `sp_backend`: set to `deepspeed` here
+- `sp_size` is the degree of the sequence parallelism - in the above example it's 4, therefore 4 gpus will be used to process a single batch (while doing DP=4 over the same gpus)
+- `sp_seq_length` and `sp_seq_length_is_variable` are used to deal with sequence lengths. If `sp_seq_length_is_variable=True` the backend will work with a sequence length that may change between batches, in which case `sp_seq_length` value can be set to anything divisible by the sequence parallel degree or not set at all. In this case on every `forward` the sequence variables will be derived from input. If `False` then `seq_length` needs to match the batch's sequence length dimension, which then will have to be padded to be always the same. The default is `True`.
+- `sp_attn_implementation` is one of `sdpa`, `flash_attention_2` or `flash_attention_3`. This sequence parallel implementation uses `position_ids` instead of `attention_mask` therefore, `eager` can't work here until it supports working with `position_ids`. Also, please note that `sdpa` doesn't handle multiple samples combined into one correctly; it will attend to the whole sample as one. If the samples aren't combined, `sdpa` will work correctly. Therefore, Flash Attention should be the ideal choice as it always works.
+
+Instead of setting these values in `DeepSpeedSequenceParallelConfig` object, you can also use the environment variables to accomplish the same - here they are correspondingly to the end of the list above.
+- `PARALLELISM_CONFIG_SP_BACKEND`
+- `PARALLELISM_CONFIG_SP_SEQ_LENGTH`
+- `PARALLELISM_CONFIG_SP_SEQ_LENGTH_IS_VARIABLE`
+- `PARALLELISM_CONFIG_SP_ATTN_IMPLEMENTATION`
+
+If not passed in the code, `sp_size` can be set via `--parallelism_config_sp_size` CLI argument. Same for other arguments. You can also do the accelerate config file style config, e.g., for 2 GPUs:
+
+```yaml
+distributed_type: DEEPSPEED
+deepspeed_config:
+ deepspeed_config_file: path/to/ds_config.json
+machine_rank: 0
+num_machines: 1
+num_processes: 2
+parallelism_config:
+ parallelism_config_dp_replicate_size: 1
+ parallelism_config_dp_shard_size: 1 # Must satisfy: 1 × 1 × 2 = 2 num_processes
+ parallelism_config_sp_size: 2
+ parallelism_config_sp_backend: deepspeed
+ parallelism_config_sp_seq_length_is_variable: true
+ parallelism_config_sp_attn_implementation: sdpa
+
+```
+
+As mentioned earlier Ulysses sequence parallelism is normally overlayed with data parallelism - same ranks are used for feeding unique data streams and also perform Ulysses Sequence Parallelism. But you could also create replicas like so:
+
+```python
+# Example: 4 GPUs with 2D parallelism (SP=2, DP=2)
+# Ensure: dp_replicate_size × dp_shard_size × sp_size = 2 × 1 × 2 = 4 GPUs
+parallelism_config = ParallelismConfig(
+ dp_replicate_size=2,
+ dp_shard_size=1, # Explicit: no sharding within replicas
+ sp_size=2,
+ sp_backend="deepspeed",
+ sp_handler=DeepSpeedSequenceParallelConfig(...),
+)
+```
+Here we use 4 gpus, with 2 sequence parallelism replicas. Deepspeed-ZeRO is what drives the data parallelism here.
+
+Please note that a lot of magic is hidden inside [UlyssesSPDataLoaderAdapter](https://github.com/deepspeedai/DeepSpeed/blob/64c0052fa08438b4ecf4cae30af15091a92d2108/deepspeed/runtime/sequence_parallel/ulysses_sp.py#L442). It's used behind the scenes, wrapping your original DataLoader object, but you should be aware of it should you run into any problems. It also automatically injects the correct `shift_labels` into the batch dictionary, before the batch gets sharded across the participating ranks.
+
+Now the only remaining piece to start using ALST/UlyssesSP is to aggregate the loss across ranks using a differentiable `all_gather` to get the grads right. The following code does it, while also excluding any masked out with `-100` tokens, to get the correct average:
+
+```python
+sp_size = parallelism_config.sp_size if parallelism_config is not None else 1
+if sp_size > 1:
+ sp_group = accelerator.torch_device_mesh["sp"].get_group()
+ sp_world_size = parallelism_config.sp_size
+
+# Normal training loop
+for iter, batch in enumerate(dl):
+ optimizer.zero_grad()
+
+ batch = move_to_device(batch, model.device)
+ outputs = model(**batch)
+
+ # only if not using liger-kernel
+ shift_labels = batch["shift_labels"]
+ loss = unwrapped_model.loss_function(
+ logits=outputs.logits,
+ labels=None,
+ shift_labels=shift_labels,
+ vocab_size=unwrapped_model.config.vocab_size,
+ )
+
+ if sp_size > 1:
+ # differentiable weighted per-shard-loss aggregation across ranks
+ losses_per_rank = torch.distributed.nn.functional.all_gather(loss, group=sp_group)
+ # special dealing with SFT that has prompt tokens that aren't used in loss computation
+ good_tokens = (shift_labels != -100).view(-1).sum()
+ good_tokens_per_rank = torch.distributed.nn.functional.all_gather(
+ good_tokens, group=sp_group
+ )
+ # Skip ranks with zero valid tokens to avoid NaN contamination (NaN * 0 = NaN)
+ total_loss = sum(
+ losses_per_rank[rank] * good_tokens_per_rank[rank]
+ for rank in range(sp_world_size)
+ if good_tokens_per_rank[rank] > 0
+ )
+ total_good_tokens = sum(good_tokens_per_rank)
+ loss = total_loss / max(total_good_tokens, 1)
+
+ if rank == 0: accelerator.print(f"{iter}: {loss=}")
+ accelerator.log(dict(train_loss=loss, step=iter))
+
+ accelerator.backward(loss)
+ optimizer.step()
+```
+
+If you use [Liger Kernel](https://github.com/linkedin/Liger-Kernel) it already knows how to handle `shift_labels` so you don't need to go through manual loss calculation, just calling `model(**batch)` will already get the `loss` calculated and done in a very memory-efficient way. If you didn't know about Liger-Kernel - it's highly recommended to be used especially for long sequence length, since it liberates a lot of working GPU memory that can be used for handling longer sequences. For example, it performs a fused logit-loss computation, never manifesting the full logits tensor in memory.
+
+If you want to see what HF Accelerate did behind the scenes please read [this full integration tutorial](https://www.deepspeed.ai/tutorials/ulysses-alst-sequence-parallelism/).
+
+For an example of an Accelerate training loop with enabled ALST/UlyssesSP see [examples/alst_ulysses_sequence_parallelism](https://github.com/huggingface/accelerate/blob/main/examples/alst_ulysses_sequence_parallelism).
+
+[!Warning]
+> This API is quite new and still in its experimental stage. While we strive to provide a stable API, some small parts of the public API may change in the future.
+
+Since this is a Deepspeed backend the usual Deepspeed configuration applies, so you can combine sequence parallelism with optimizer states and/or weights offloading as well to liberate more gpu memory and enable an even longer sequence length. This technology has been tested to work with DeepSpeed ZeRO stage 2 and 3.
+
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/training_tpu.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/training_tpu.md
new file mode 100644
index 0000000000000000000000000000000000000000..97f799179bd4f113f6a0ad564a727a5b1bf03edd
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/concept_guides/training_tpu.md
@@ -0,0 +1,167 @@
+
+
+# Training on TPUs
+
+Training on TPUs can be slightly different from training on multi-gpu, even with Accelerate. This guide aims to show you
+where you should be careful and why, as well as the best practices in general.
+
+## Training in a Notebook
+
+The main carepoint when training on TPUs comes from the [`notebook_launcher`]. As mentioned in the [notebook tutorial](../usage_guides/notebook), you need to
+restructure your training code into a function that can get passed to the [`notebook_launcher`] function and be careful about not declaring any tensors on the GPU.
+
+While on a TPU that last part is not as important, a critical part to understand is that when you launch code from a notebook you do so through a process called **forking**.
+When launching from the command-line, you perform **spawning**, where a python process is not currently running and you *spawn* a new process in. Since your Jupyter notebook is already
+utilizing a python process, you need to *fork* a new process from it to launch your code.
+
+Where this becomes important is in regard to declaring your model. On forked TPU processes, it is recommended that you instantiate your model *once* and pass this into your
+training function. This is different than training on GPUs where you create `n` models that have their gradients synced and back-propagated at certain moments. Instead, one
+model instance is shared between all the nodes and it is passed back and forth. This is important especially when training on low-resource TPUs such as those provided in Kaggle kernels or
+on Google Colaboratory.
+
+Below is an example of a training function passed to the [`notebook_launcher`] if training on CPUs or GPUs:
+
+
+
+ This code snippet is based off the one from the `simple_nlp_example` notebook found [here](https://github.com/huggingface/notebooks/blob/main/examples/accelerate_examples/simple_nlp_example.ipynb) with slight
+ modifications for the sake of simplicity
+
+
+
+```python
+def training_function():
+ # Initialize accelerator
+ accelerator = Accelerator()
+ model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", num_labels=2)
+ train_dataloader, eval_dataloader = create_dataloaders(
+ train_batch_size=hyperparameters["train_batch_size"], eval_batch_size=hyperparameters["eval_batch_size"]
+ )
+
+ # Instantiate optimizer
+ optimizer = AdamW(params=model.parameters(), lr=hyperparameters["learning_rate"])
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader
+ )
+
+ num_epochs = hyperparameters["num_epochs"]
+ # Now we train the model
+ for epoch in range(num_epochs):
+ model.train()
+ for step, batch in enumerate(train_dataloader):
+ outputs = model(**batch)
+ loss = outputs.loss
+ accelerator.backward(loss)
+
+ optimizer.step()
+ optimizer.zero_grad()
+```
+
+```python
+from accelerate import notebook_launcher
+
+notebook_launcher(training_function)
+```
+
+
+
+ The `notebook_launcher` will default to 8 processes if Accelerate has been configured for a TPU
+
+
+
+If you use this example and declare the model *inside* the training loop, then on a low-resource system you will potentially see an error
+like:
+
+```
+ProcessExitedException: process 0 terminated with signal SIGSEGV
+```
+
+This error is *extremely* cryptic but the basic explanation is you ran out of system RAM. You can avoid this entirely by reconfiguring the training function to
+accept a single `model` argument, and declare it in an outside cell:
+
+```python
+# In another Jupyter cell
+model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", num_labels=2)
+```
+
+```diff
++ def training_function(model):
+ # Initialize accelerator
+ accelerator = Accelerator()
+- model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", num_labels=2)
+ train_dataloader, eval_dataloader = create_dataloaders(
+ train_batch_size=hyperparameters["train_batch_size"], eval_batch_size=hyperparameters["eval_batch_size"]
+ )
+ ...
+```
+
+And finally calling the training function with:
+
+```diff
+ from accelerate import notebook_launcher
+- notebook_launcher(training_function)
++ notebook_launcher(training_function, (model,))
+```
+
+
+
+ The above workaround is only needed when launching a TPU instance from a Jupyter Notebook on a low-resource server such as Google Colaboratory or Kaggle. If
+ using a script or launching on a much beefier server declaring the model beforehand is not needed.
+
+
+
+## Mixed Precision and Global Variables
+
+As mentioned in the [mixed precision tutorial](../usage_guides/mixed_precision), Accelerate supports fp16 and bf16, both of which can be used on TPUs.
+That being said, ideally `bf16` should be utilized as it is extremely efficient to use.
+
+There are two "layers" when using `bf16` and Accelerate on TPUs, at the base level and at the operation level.
+
+At the base level, this is enabled when passing `mixed_precision="bf16"` to `Accelerator`, such as:
+```python
+accelerator = Accelerator(mixed_precision="bf16")
+```
+By default, this will cast `torch.float` and `torch.double` to `bfloat16` on TPUs.
+The specific configuration being set is an environmental variable of `XLA_USE_BF16` is set to `1`.
+
+There is a further configuration you can perform which is setting the `XLA_DOWNCAST_BF16` environmental variable. If set to `1`, then
+`torch.float` is `bfloat16` and `torch.double` is `float32`.
+
+This is performed in the `Accelerator` object when passing `downcast_bf16=True`:
+```python
+accelerator = Accelerator(mixed_precision="bf16", downcast_bf16=True)
+```
+
+Using downcasting instead of bf16 everywhere is good for when you are trying to calculate metrics, log values, and more where raw bf16 tensors would be unusable.
+
+## Training Times on TPUs
+
+As you launch your script, you may notice that training seems exceptionally slow at first. This is because TPUs
+first run through a few batches of data to see how much memory to allocate before finally utilizing this configured
+memory allocation extremely efficiently.
+
+If you notice that your evaluation code to calculate the metrics of your model takes longer due to a larger batch size being used,
+it is recommended to keep the batch size the same as the training data if it is too slow. Otherwise the memory will reallocate to this
+new batch size after the first few iterations.
+
+
+
+ Just because the memory is allocated does not mean it will be used or that the batch size will increase when going back to your training dataloader.
+
+
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/imgs/accelerate_logo.png b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/imgs/accelerate_logo.png
new file mode 100644
index 0000000000000000000000000000000000000000..c8d2659132eb4b4b6c0e5438335477720e89198e
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/imgs/accelerate_logo.png
@@ -0,0 +1,3 @@
+version https://git-lfs.github.com/spec/v1
+oid sha256:5ab00c5c1a233390ec3161c39b7c2d529043f1eddc7f66954392f614d5d7a81d
+size 12653
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/imgs/course_banner.png b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/imgs/course_banner.png
new file mode 100644
index 0000000000000000000000000000000000000000..95093b20769aabaffc86b26e7d92ebf1022a41be
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/imgs/course_banner.png
@@ -0,0 +1,3 @@
+version https://git-lfs.github.com/spec/v1
+oid sha256:809c043430c67617f0f1b1551f51cee564a4b3cce938d34b4eb478dc94a63280
+size 80305
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/imgs/profile_export.png b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/imgs/profile_export.png
new file mode 100644
index 0000000000000000000000000000000000000000..39fff39eaaf06a7daa2a5cba90b5c6d0b7aded5f
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/imgs/profile_export.png
@@ -0,0 +1,3 @@
+version https://git-lfs.github.com/spec/v1
+oid sha256:f96bb5d988aefa89b480c40f83a11b543c185804e7c15f9574f14ff45514ec2e
+size 107863
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/index.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/index.md
new file mode 100644
index 0000000000000000000000000000000000000000..28db7a0801cbff4fddb3c667f4174ca6f816d613
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/index.md
@@ -0,0 +1,74 @@
+
+
+# Accelerate
+
+Accelerate is a library that enables the same PyTorch code to be run across any distributed configuration by adding just four lines of code! In short, training and inference at scale made simple, efficient and adaptable.
+
+```diff
++ from accelerate import Accelerator
++ accelerator = Accelerator()
+
++ model, optimizer, training_dataloader, scheduler = accelerator.prepare(
++ model, optimizer, training_dataloader, scheduler
++ )
+
+ for batch in training_dataloader:
+ optimizer.zero_grad()
+ inputs, targets = batch
+ inputs = inputs.to(device)
+ targets = targets.to(device)
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets)
++ accelerator.backward(loss)
+ optimizer.step()
+ scheduler.step()
+```
+
+Built on `torch_xla` and `torch.distributed`, Accelerate takes care of the heavy lifting, so you don't have to write any custom code to adapt to these platforms.
+Convert existing codebases to utilize [DeepSpeed](usage_guides/deepspeed), perform [fully sharded data parallelism](usage_guides/fsdp), and have automatic support for mixed-precision training!
+
+
+
+ To get a better idea of this process, make sure to check out the [Tutorials](basic_tutorials/overview)!
+
+
+
+
+This code can then be launched on any system through Accelerate's CLI interface:
+```bash
+accelerate launch {my_script.py}
+```
+
+
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/accelerator.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/accelerator.md
new file mode 100644
index 0000000000000000000000000000000000000000..7d915a4ee60e5518f1f652f549476ed286e98e10
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/accelerator.md
@@ -0,0 +1,26 @@
+
+
+# Accelerator
+
+The [`Accelerator`] is the main class for enabling distributed training on any type of training setup. Read the [Add Accelerator to your code](../basic_tutorials/migration) tutorial to learn more about how to add the [`Accelerator`] to your script.
+
+## Accelerator[[api]]
+
+[[autodoc]] Accelerator
+
+## Utilities
+
+[[autodoc]] accelerate.utils.gather_object
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/big_modeling.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/big_modeling.md
new file mode 100644
index 0000000000000000000000000000000000000000..c599a28c73e3d66e75a86a74e3bab9df5a7e5681
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/big_modeling.md
@@ -0,0 +1,110 @@
+
+
+# Working with large models
+
+## Dispatch and offload
+
+### init_empty_weights
+
+[[autodoc]] big_modeling.init_empty_weights
+
+### cpu_offload
+
+[[autodoc]] big_modeling.cpu_offload
+
+### cpu_offload_with_hook
+
+[[autodoc]] big_modeling.cpu_offload_with_hook
+
+### disk_offload
+
+[[autodoc]] big_modeling.disk_offload
+
+### dispatch_model
+
+[[autodoc]] big_modeling.dispatch_model
+
+### load_checkpoint_and_dispatch
+
+[[autodoc]] big_modeling.load_checkpoint_and_dispatch
+
+### load_checkpoint_in_model
+
+[[autodoc]] big_modeling.load_checkpoint_in_model
+
+### infer_auto_device_map
+
+[[autodoc]] utils.infer_auto_device_map
+
+## Hooks
+
+### ModelHook
+
+[[autodoc]] hooks.ModelHook
+
+### AlignDevicesHook
+
+[[autodoc]] hooks.AlignDevicesHook
+
+### SequentialHook
+
+[[autodoc]] hooks.SequentialHook
+
+### LayerwiseCastingHook
+
+[[autodoc]] hooks.LayerwiseCastingHook
+
+## Adding Hooks
+
+### add_hook_to_module
+
+[[autodoc]] hooks.add_hook_to_module
+
+### attach_execution_device_hook
+
+[[autodoc]] hooks.attach_execution_device_hook
+
+### attach_align_device_hook
+
+[[autodoc]] hooks.attach_align_device_hook
+
+### attach_align_device_hook_on_blocks
+
+[[autodoc]] hooks.attach_align_device_hook_on_blocks
+
+### attach_layerwise_casting_hooks
+
+[[autodoc]] big_modeling.attach_layerwise_casting_hooks
+
+## Removing Hooks
+
+### remove_hook_from_module
+
+[[autodoc]] hooks.remove_hook_from_module
+
+### remove_hook_from_submodules
+
+[[autodoc]] hooks.remove_hook_from_submodules
+
+## Utilities
+
+### has_offloaded_params
+
+[[autodoc]] utils.has_offloaded_params
+
+### align_module_device
+
+[[autodoc]] utils.align_module_device
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/cli.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/cli.md
new file mode 100644
index 0000000000000000000000000000000000000000..14e0a66ccab18a6bb9fa678c4a2aa37d4c6ad907
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/cli.md
@@ -0,0 +1,335 @@
+
+
+# The Command Line
+
+Below is a list of all the available commands 🤗 Accelerate with their parameters
+
+## accelerate config
+
+**Command**:
+
+`accelerate config` or `accelerate-config`
+
+Launches a series of prompts to create and save a `default_config.yml` configuration file for your training system. Should
+always be ran first on your machine.
+
+**Usage**:
+
+```bash
+accelerate config [arguments]
+```
+
+**Optional Arguments**:
+* `--config_file CONFIG_FILE` (`str`) -- The path to use to store the config file. Will default to a file named default_config.yaml in the cache location, which is the content
+ of the environment `HF_HOME` suffixed with 'accelerate', or if you don't have such an environment variable, your cache directory
+ (`~/.cache` or the content of `XDG_CACHE_HOME`) suffixed with `huggingface`.
+* `-h`, `--help` (`bool`) -- Show a help message and exit
+
+## accelerate config default
+
+**Command**:
+
+`accelerate config default` or `accelerate-config default`
+
+Create a default config file for Accelerate with only a few flags set.
+
+**Usage**:
+
+```bash
+accelerate config default [arguments]
+```
+
+**Optional Arguments**:
+* `--config_file CONFIG_FILE` (`str`) -- The path to use to store the config file. Will default to a file named default_config.yaml in the cache location, which is the content
+ of the environment `HF_HOME` suffixed with 'accelerate', or if you don't have such an environment variable, your cache directory
+ (`~/.cache` or the content of `XDG_CACHE_HOME`) suffixed with `huggingface`.
+
+* `-h`, `--help` (`bool`) -- Show a help message and exit
+* `--mixed_precision {no,fp16,bf16}` (`str`) -- Whether or not to use mixed precision training. Choose between FP16 and BF16 (bfloat16) training. BF16 training is only supported on Nvidia Ampere GPUs and PyTorch 1.10 or later.
+
+## accelerate config update
+
+**Command**:
+
+`accelerate config update` or `accelerate-config update`
+
+Update an existing config file with the latest defaults while maintaining the old configuration.
+
+**Usage**:
+
+```bash
+accelerate config update [arguments]
+```
+
+**Optional Arguments**:
+* `--config_file CONFIG_FILE` (`str`) -- The path to the config file to update. Will default to a file named default_config.yaml in the cache location, which is the content
+ of the environment `HF_HOME` suffixed with 'accelerate', or if you don't have such an environment variable, your cache directory
+ (`~/.cache` or the content of `XDG_CACHE_HOME`) suffixed with `huggingface`.
+
+* `-h`, `--help` (`bool`) -- Show a help message and exit
+
+
+## accelerate env
+
+**Command**:
+
+`accelerate env` or `accelerate-env` or `python -m accelerate.commands.env`
+
+Lists the contents of the passed 🤗 Accelerate configuration file. Should always be used when opening an issue on the [GitHub repository](https://github.com/huggingface/accelerate).
+
+**Usage**:
+
+```bash
+accelerate env [arguments]
+```
+
+**Optional Arguments**:
+* `--config_file CONFIG_FILE` (`str`) -- The path to use to store the config file. Will default to a file named default_config.yaml in the cache location, which is the content
+ of the environment `HF_HOME` suffixed with 'accelerate', or if you don't have such an environment variable, your cache directory
+ (`~/.cache` or the content of `XDG_CACHE_HOME`) suffixed with `huggingface`.
+* `-h`, `--help` (`bool`) -- Show a help message and exit
+
+## accelerate launch
+
+**Command**:
+
+`accelerate launch` or `accelerate-launch` or `python -m accelerate.commands.launch`
+
+Launches a specified script on a distributed system with the right parameters.
+
+**Usage**:
+
+```bash
+accelerate launch [arguments] {training_script} --{training_script-argument-1} --{training_script-argument-2} ...
+```
+
+**Positional Arguments**:
+
+- `{training_script}` -- The full path to the script to be launched in parallel
+- `--{training_script-argument-1}` -- Arguments of the training script
+
+**Optional Arguments**:
+
+* `-h`, `--help` (`bool`) -- Show a help message and exit
+* `--config_file CONFIG_FILE` (`str`)-- The config file to use for the default values in the launching script.
+* `-m`, `--module` (`bool`) -- Change each process to interpret the launch script as a Python module, executing with the same behavior as 'python -m'.
+* `--no_python` (`bool`) -- Skip prepending the training script with 'python' - just execute it directly. Useful when the script is not a Python script.
+* `--debug` (`bool`) -- Whether to print out the torch.distributed stack trace when something fails.
+* `-q`, `--quiet` (`bool`) -- Silence subprocess errors from the launch stack trace to only show the relevant tracebacks. (Only applicable to DeepSpeed and single-process configurations).
+
+
+The rest of these arguments are configured through `accelerate config` and are read in from the specified `--config_file` (or default configuration) for their
+values. They can also be passed in manually.
+
+**Hardware Selection Arguments**:
+
+* `--cpu` (`bool`) -- Whether or not to force the training on the CPU.
+* `--multi_gpu` (`bool`) -- Whether or not this should launch a distributed GPU training.
+* `--tpu` (`bool`) -- Whether or not this should launch a TPU training.
+* `--ipex` (`bool`) -- Whether or not this should launch an Intel Pytorch Extension (IPEX) training. **This argument is deprecated, will be removed in Accelerate v1.10**
+
+**Resource Selection Arguments**:
+
+The following arguments are useful for fine-tuning how available hardware should be used
+
+* `--mixed_precision {no,fp16,bf16,fp8}` (`str`) -- Whether or not to use mixed precision training. Choose between FP16 and BF16 (bfloat16) training. BF16 training is only supported on Nvidia Ampere GPUs and PyTorch 1.10 or later.
+* `--num_processes NUM_PROCESSES` (`int`) -- The total number of processes to be launched in parallel.
+* `--num_machines NUM_MACHINES` (`int`) -- The total number of machines used in this training.
+* `--num_cpu_threads_per_process NUM_CPU_THREADS_PER_PROCESS` (`int`) -- The number of CPU threads per process. Can be tuned for optimal performance.
+* `--enable_cpu_affinity` (`bool`) -- Whether or not CPU affinity and balancing should be enabled. Currently only supported on NVIDIA hardware.
+
+**Training Paradigm Arguments**:
+
+The following arguments are useful for selecting which training paradigm to use.
+
+* `--use_deepspeed` (`bool`) -- Whether or not to use DeepSpeed for training.
+* `--use_fsdp` (`bool`) -- Whether or not to use FullyShardedDataParallel for training.
+* `--use_megatron_lm` (`bool`) -- Whether or not to use Megatron-LM for training.
+* `--use_xpu` (`bool`) -- Whether to use IPEX plugin to speed up training on XPU specifically. **This argument is deprecated and ignored, will be removed in Accelerate v1.10**
+
+**Distributed GPU Arguments**:
+
+The following arguments are only useful when `multi_gpu` is passed or multi-gpu training is configured through `accelerate config`:
+
+* `--gpu_ids` (`str`) -- What GPUs (by id) should be used for training on this machine as a comma-separated list
+* `--same_network` (`bool`) -- Whether all machines used for multinode training exist on the same local network.
+* `--machine_rank` (`int`) -- The rank of the machine on which this script is launched.
+* `--main_process_ip` (`str`) -- The IP address of the machine of rank 0.
+* `--main_process_port` (`int`) -- The port to use to communicate with the machine of rank 0.
+* `-t`, `--tee` (`str`) -- Tee std streams into a log file and also to console.
+* `--log_dir` (`str`) -- Base directory to use for log files when using torchrun/torch.distributed.run as launcher. Use with --tee to redirect std streams info log files.
+* `--role` (`str`) -- User-defined role for the workers.
+* `--rdzv_backend` (`str`) -- The rendezvous method to use, such as 'static' (the default) or 'c10d'
+* `--rdzv_conf` (`str`) -- Additional rendezvous configuration (=,=,...).
+* `--max_restarts` (`int`) -- Maximum number of worker group restarts before failing.
+* `--monitor_interval` (`int`) -- Interval, in seconds, to monitor the state of workers.
+
+**TPU Arguments**:
+
+The following arguments are only useful when `tpu` is passed or TPU training is configured through `accelerate config`:
+
+* `--tpu_cluster` (`bool`) -- Whether to use a GCP TPU pod for training.
+* `--tpu_use_sudo` (`bool`) -- Whether to use `sudo` when running the TPU training script in each pod.
+* `--vm` (`str`) -- List of single Compute VM instance names. If not provided we assume usage of instance groups. For TPU pods.
+* `--env` (`str`) -- List of environment variables to set on the Compute VM instances. For TPU pods.
+* `--main_training_function` (`str`) -- The name of the main function to be executed in your script (only for TPU training).
+* `--downcast_bf16` (`bool`) -- Whether when using bf16 precision on TPUs if both float and double tensors are cast to bfloat16 or if double tensors remain as float32.
+
+**DeepSpeed Arguments**:
+
+The following arguments are only useful when `use_deepspeed` is passed or `deepspeed` is configured through `accelerate config`:
+
+* `--deepspeed_config_file` (`str`) -- DeepSpeed config file.
+* `--zero_stage` (`int`) -- DeepSpeed's ZeRO optimization stage.
+* `--offload_optimizer_device` (`str`) -- Decides where (none|cpu|nvme) to offload optimizer states.
+* `--offload_param_device` (`str`) -- Decides where (none|cpu|nvme) to offload parameters.
+* `--offload_optimizer_nvme_path` (`str`) -- Decides Nvme Path to offload optimizer states.
+* `--gradient_accumulation_steps` (`int`) -- No of gradient_accumulation_steps used in your training script.
+* `--gradient_clipping` (`float`) -- Gradient clipping value used in your training script.
+* `--zero3_init_flag` (`str`) -- Decides Whether (true|false) to enable `deepspeed.zero.Init` for constructing massive models. Only applicable with DeepSpeed ZeRO Stage-3.
+* `--zero3_save_16bit_model` (`str`) -- Decides Whether (true|false) to save 16-bit model weights when using ZeRO Stage-3. Only applicable with DeepSpeed ZeRO Stage-3.
+* `--deepspeed_hostfile` (`str`) -- DeepSpeed hostfile for configuring multi-node compute resources.
+* `--deepspeed_exclusion_filter` (`str`) -- DeepSpeed exclusion filter string when using multi-node setup.
+* `--deepspeed_inclusion_filter` (`str`) -- DeepSpeed inclusion filter string when using multi-node setup.
+* `--deepspeed_multinode_launcher` (`str`) -- DeepSpeed multi-node launcher to use.
+* `--deepspeed_moe_layer_cls_names` (`str`) -- comma-separated list of transformer MoE layer class names (case-sensitive) to wrap, e.g, `MixtralSparseMoeBlock` `Qwen2MoeSparseMoeBlock`, `JetMoEAttention,JetMoEBlock`
+
+**Fully Sharded Data Parallelism Arguments**:
+
+The following arguments are only useful when `use_fsdp` is passed or Fully Sharded Data Parallelism is configured through `accelerate config`:
+
+* `--fsdp_offload_params` (`str`) -- Decides Whether (true|false) to offload parameters and gradients to CPU.
+* `--fsdp_min_num_params` (`int`) -- FSDP's minimum number of parameters for Default Auto Wrapping.
+* `--fsdp_sharding_strategy` (`int`) -- FSDP's Sharding Strategy.
+* `--fsdp_auto_wrap_policy` (`str`) -- FSDP's auto wrap policy.
+* `--fsdp_transformer_layer_cls_to_wrap` (`str`) -- Transformer layer class name (case-sensitive) to wrap, e.g, `BertLayer`, `GPTJBlock`, `T5Block` ...
+* `--fsdp_backward_prefetch_policy` (`str`) -- FSDP's backward prefetch policy.
+* `--fsdp_state_dict_type` (`str`) -- FSDP's state dict type.
+* `--fsdp_forward_prefetch` (`str`) -- FSDP forward prefetch.
+* `--fsdp_use_orig_params` (`str`) -- If True, allows non-uniform `requires_grad` mixed in a FSDP unit.
+* `--fsdp_cpu_ram_efficient_loading` (`str`) -- If true, only the first process loads the pretrained model checkoint while all other processes have empty weights. When using this, `--fsdp_sync_module_states` needs to True.
+* `--fsdp_sync_module_states` (`str`) -- If true, each individually wrapped FSDP unit will broadcast module parameters from rank 0.
+* `--fsdp_activation_checkpointing` (`bool`) -- Decides Whether intermediate activations are freed during the forward pass, and a checkpoint is left as a placeholder
+
+**Megatron-LM Arguments**:
+
+The following arguments are only useful when `use_megatron_lm` is passed or Megatron-LM is configured through `accelerate config`:
+
+* `--megatron_lm_tp_degree` (``) -- Megatron-LM's Tensor Parallelism (TP) degree.
+* `--megatron_lm_pp_degree` (``) -- Megatron-LM's Pipeline Parallelism (PP) degree.
+* `--megatron_lm_num_micro_batches` (``) -- Megatron-LM's number of micro batches when PP degree > 1.
+* `--megatron_lm_sequence_parallelism` (``) -- Decides Whether (true|false) to enable Sequence Parallelism when TP degree > 1.
+* `--megatron_lm_recompute_activations` (``) -- Decides Whether (true|false) to enable Selective Activation Recomputation.
+* `--megatron_lm_use_distributed_optimizer` (``) -- Decides Whether (true|false) to use distributed optimizer which shards optimizer state and gradients across Data Parallel (DP) ranks.
+* `--megatron_lm_gradient_clipping` (``) -- Megatron-LM's gradient clipping value based on global L2 Norm (0 to disable).
+
+**FP8 Arguments**:
+
+* `--fp8_backend` (`str`) -- Choose a backend to train with FP8 (`te` or `msamp`)
+* `--fp8_use_autocast_during_eval` (`bool`) -- Whether to use FP8 autocast during eval mode (useful only when `--fp8_backend=te` is passed). Generally better metrics are found when this is not passed.
+* `--fp8_margin` (`int`) -- The margin to use for the gradient scaling (useful only when `--fp8_backend=te` is passed).
+* `--fp8_interval` (`int`) -- The interval to use for how often the scaling factor is recomputed (useful only when `--fp8_backend=te` is passed).
+* `--fp8_format` (`str`) -- The format to use for the FP8 recipe (useful only when `--fp8_backend=te` is passed).
+* `--fp8_amax_history_len` (`int`) -- The length of the history to use for the scaling factor computation (useful only when `--fp8_backend=te` is passed).
+* `--fp8_amax_compute_algo` (`str`) -- The algorithm to use for the scaling factor computation. (useful only when `--fp8_backend=te` is passed).
+* `--fp8_override_linear_precision` (`Tuple[bool, bool, bool]`) -- Whether or not to execute `fprop`, `dgrad`, and `wgrad` GEMMS in higher precision.
+* `--fp8_opt_level` (`str`) -- What level of 8-bit collective communication should be used with MS-AMP (useful only when `--fp8_backend=msamp` is passed)
+
+**AWS SageMaker Arguments**:
+
+The following arguments are only useful when training in SageMaker
+
+* `--aws_access_key_id AWS_ACCESS_KEY_ID` (`str`) -- The AWS_ACCESS_KEY_ID used to launch the Amazon SageMaker training job
+* `--aws_secret_access_key AWS_SECRET_ACCESS_KEY` (`str`) -- The AWS_SECRET_ACCESS_KEY used to launch the Amazon SageMaker training job
+
+## accelerate estimate-memory
+
+**Command**:
+
+`accelerate estimate-memory` or `accelerate-estimate-memory` or `python -m accelerate.commands.estimate`
+
+Estimates the total vRAM a particular model hosted on the Hub needs to be loaded in with an estimate for training. Requires that `huggingface_hub` be installed.
+
+
+
+ When performing inference, typically add ≤20% to the result as overall allocation [as referenced here](https://blog.eleuther.ai/transformer-math/). We will have more extensive estimations in the future that will automatically be included in the calculation.
+
+
+
+**Usage**:
+
+```bash
+accelerate estimate-memory {MODEL_NAME} --library_name {LIBRARY_NAME} --dtypes {dtype_1} {dtype_2} ...
+```
+
+**Required Arguments**:
+
+* `MODEL_NAME` (`str`)-- The model name on the Hugging Face Hub
+
+**Optional Arguments**:
+
+* `--library_name {timm,transformers}` (`str`) -- The library the model has an integration with, such as `transformers`, needed only if this information is not stored on the Hub
+* `--dtypes {float32,float16,int8,int4}` (`[{float32,float16,int8,int4} ...]`) -- The dtypes to use for the model, must be one (or many) of `float32`, `float16`, `int8`, and `int4`
+* `--trust_remote_code` (`bool`) -- Whether or not to allow for custom models defined on the Hub in their own modeling files. This option should only be passed for repositories you trust and in which you have read the code, as it will execute code present on the Hub on your local machine.
+
+## accelerate tpu-config
+
+`accelerate tpu-config`
+
+**Usage**:
+
+```bash
+accelerate tpu-config [arguments]
+```
+
+**Optional Arguments**:
+* `-h`, `--help` (`bool`) -- Show a help message and exit
+
+**Config Arguments**:
+
+Arguments that can be configured through `accelerate config`.
+
+* `--config_file` (`str`) -- Path to the config file to use for accelerate.
+* `--tpu_name` (`str`) -- The name of the TPU to use. If not specified, will use the TPU specified in the config file.
+* `--tpu_zone` (`str`) -- The zone of the TPU to use. If not specified, will use the zone specified in the config file.
+
+**TPU Arguments**:
+
+Arguments for options ran inside the TPU.
+
+* `--command_file` (`str`) -- The path to the file containing the commands to run on the pod on startup.
+* `--command` (`str`) -- A command to run on the pod. Can be passed multiple times.
+* `--install_accelerate` (`bool`) -- Whether to install accelerate on the pod. Defaults to False.
+* `--accelerate_version` (`str`) -- The version of accelerate to install on the pod. If not specified, will use the latest pypi version. Specify 'dev' to install from GitHub.
+* `--debug` (`bool`) -- If set, will print the command that would be run instead of running it.
+
+## accelerate test
+
+`accelerate test` or `accelerate-test`
+
+Runs `accelerate/test_utils/test_script.py` to verify that 🤗 Accelerate has been properly configured on your system and runs.
+
+**Usage**:
+
+```bash
+accelerate test [arguments]
+```
+
+**Optional Arguments**:
+* `--config_file CONFIG_FILE` (`str`) -- The path to use to store the config file. Will default to a file named default_config.yaml in the cache location, which is the content
+ of the environment `HF_HOME` suffixed with 'accelerate', or if you don't have such an environment variable, your cache directory
+ (`~/.cache` or the content of `XDG_CACHE_HOME`) suffixed with `huggingface`.
+* `-h`, `--help` (`bool`) -- Show a help message and exit
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/deepspeed.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/deepspeed.md
new file mode 100644
index 0000000000000000000000000000000000000000..e8e27f9c41bf924ced312978e612c8938d37c66b
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/deepspeed.md
@@ -0,0 +1,44 @@
+
+
+# DeepSpeed utilities
+
+## DeepSpeedPlugin
+
+## get_active_deepspeed_plugin
+
+[[autodoc]] utils.get_active_deepspeed_plugin
+
+[[autodoc]] utils.DeepSpeedPlugin
+
+[[autodoc]] utils.deepspeed.DummyScheduler
+
+## DeepSpeedEnginerWrapper
+
+[[autodoc]] utils.deepspeed.DeepSpeedEngineWrapper
+
+## DeepSpeedOptimizerWrapper
+
+[[autodoc]] utils.deepspeed.DeepSpeedOptimizerWrapper
+
+## DeepSpeedSchedulerWrapper
+
+[[autodoc]] utils.deepspeed.DeepSpeedSchedulerWrapper
+
+## DummyOptim
+
+[[autodoc]] utils.deepspeed.DummyOptim
+
+## DummyScheduler
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/fp8.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/fp8.md
new file mode 100644
index 0000000000000000000000000000000000000000..2b3420f5d708920d1bc5a6dba37fd45b1633c15b
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/fp8.md
@@ -0,0 +1,38 @@
+
+
+# FP8
+
+Below are functions and classes relative to the underlying FP8 implementation
+
+## FP8RecipeKwargs
+
+[[autodoc]] utils.FP8RecipeKwargs
+
+## convert_model
+
+[[autodoc]] utils.convert_model
+
+## has_transformer_engine_layers
+
+[[autodoc]] utils.has_transformer_engine_layers
+
+## contextual_fp8_autocast
+
+[[autodoc]] utils.contextual_fp8_autocast
+
+## apply_fp8_autowrap
+
+[[autodoc]] utils.apply_fp8_autowrap
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/fsdp.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/fsdp.md
new file mode 100644
index 0000000000000000000000000000000000000000..e4cdb04b176a480279faa93de7a02a2161f9767b
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/fsdp.md
@@ -0,0 +1,46 @@
+
+
+# Fully Sharded Data Parallel utilities
+
+## enable_fsdp_ram_efficient_loading
+
+[[autodoc]] utils.enable_fsdp_ram_efficient_loading
+
+## disable_fsdp_ram_efficient_loading
+
+[[autodoc]] utils.disable_fsdp_ram_efficient_loading
+
+## merge_fsdp_weights
+
+[[autodoc]] utils.merge_fsdp_weights
+
+## FullyShardedDataParallelPlugin
+
+[[autodoc]] utils.FullyShardedDataParallelPlugin
+
+## fsdp2_load_full_state_dict
+
+[[autodoc]] utils.fsdp2_load_full_state_dict
+
+## fsdp2_switch_optimizer_parameters
+
+[[autodoc]] utils.fsdp2_switch_optimizer_parameters
+
+## fsdp2_prepare_model
+
+[[autodoc]] utils.fsdp2_prepare_model
+
+## fsdp2_prepare_auto_wrap_policy
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/inference.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/inference.md
new file mode 100644
index 0000000000000000000000000000000000000000..5e41646b94d46a8009f41980a1b55b5dff3c9845
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/inference.md
@@ -0,0 +1,22 @@
+
+
+# Pipeline parallelism
+
+Accelerate supports pipeline parallelism for large-scale training with the PyTorch [torch.distributed.pipelining](https://pytorch.org/docs/stable/distributed.pipelining.html) API.
+
+## prepare_pippy
+
+[[autodoc]] inference.prepare_pippy
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/kwargs.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/kwargs.md
new file mode 100644
index 0000000000000000000000000000000000000000..a2ecf966c12b0e2ce8f1dec1cab218faff4ca905
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/kwargs.md
@@ -0,0 +1,47 @@
+
+
+# Kwargs handlers
+
+The following objects can be passed to the main [`Accelerator`] to customize how some PyTorch objects
+related to distributed training or mixed precision are created.
+
+## AutocastKwargs
+
+[[autodoc]] AutocastKwargs
+
+## DistributedDataParallelKwargs
+
+[[autodoc]] DistributedDataParallelKwargs
+
+## FP8RecipeKwargs
+
+[[autodoc]] utils.FP8RecipeKwargs
+
+## ProfileKwargs
+
+[[autodoc]] utils.ProfileKwargs
+
+## GradScalerKwargs
+
+[[autodoc]] GradScalerKwargs
+
+## InitProcessGroupKwargs
+
+[[autodoc]] InitProcessGroupKwargs
+
+## KwargsHandler
+
+[[autodoc]] utils.KwargsHandler
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/launchers.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/launchers.md
new file mode 100644
index 0000000000000000000000000000000000000000..7da4087c853396e081c289ea261175c170159ce4
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/launchers.md
@@ -0,0 +1,26 @@
+
+
+# Launchers
+
+Functions for launching training on distributed processes.
+
+## notebook_launcher
+
+[[autodoc]] accelerate.notebook_launcher
+
+## debug_launcher
+
+[[autodoc]] accelerate.debug_launcher
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/logging.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/logging.md
new file mode 100644
index 0000000000000000000000000000000000000000..ef02060654b656e46660079e744da1696e85aae6
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/logging.md
@@ -0,0 +1,21 @@
+
+
+# Logging
+
+Refer to the [Troubleshooting guide](../usage_guides/troubleshooting#logging) or to the example below to learn
+how to use Accelerate's logger.
+
+[[autodoc]] logging.get_logger
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/megatron_lm.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/megatron_lm.md
new file mode 100644
index 0000000000000000000000000000000000000000..cddabdde9bbe1d0a4b8d9c0b863f61f941245905
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/megatron_lm.md
@@ -0,0 +1,48 @@
+
+
+# Megatron-LM utilities
+
+## MegatronLMPlugin
+
+[[autodoc]] utils.MegatronLMPlugin
+
+## MegatronLMDummyScheduler
+
+[[autodoc]] utils.MegatronLMDummyScheduler
+
+## MegatronLMDummyDataLoader
+
+[[autodoc]] utils.MegatronLMDummyDataLoader
+
+## AbstractTrainStep
+
+[[autodoc]] utils.AbstractTrainStep
+
+## GPTTrainStep
+
+[[autodoc]] utils.GPTTrainStep
+
+## BertTrainStep
+
+[[autodoc]] utils.BertTrainStep
+
+## T5TrainStep
+
+[[autodoc]] utils.T5TrainStep
+
+## avg_losses_across_data_parallel_group
+
+[[autodoc]] utils.avg_losses_across_data_parallel_group
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/state.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/state.md
new file mode 100644
index 0000000000000000000000000000000000000000..2cdd94b82e0ee68a0895d66bc81809e3144c8b8d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/state.md
@@ -0,0 +1,34 @@
+
+
+# Stateful Classes
+
+Below are variations of a [singleton class](https://en.wikipedia.org/wiki/Singleton_pattern) in the sense that all
+instances share the same state, which is initialized on the first instantiation.
+
+These classes are immutable and store information about certain configurations or
+states.
+
+## PartialState
+
+[[autodoc]] state.PartialState
+
+## AcceleratorState
+
+[[autodoc]] state.AcceleratorState
+
+## GradientState
+
+[[autodoc]] state.GradientState
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/torch_wrappers.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/torch_wrappers.md
new file mode 100644
index 0000000000000000000000000000000000000000..84c88bca7e4c2d8755439cf8005dd29f0dbfa026
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/torch_wrappers.md
@@ -0,0 +1,48 @@
+
+
+# DataLoaders, Optimizers, and Schedulers
+
+The internal classes Accelerate uses to prepare objects for distributed training
+when calling [`~Accelerator.prepare`].
+
+## DataLoader utilities
+
+[[autodoc]] data_loader.prepare_data_loader
+[[autodoc]] data_loader.skip_first_batches
+
+## BatchSamplerShard
+
+[[autodoc]] data_loader.BatchSamplerShard
+
+## IterableDatasetShard
+
+[[autodoc]] data_loader.IterableDatasetShard
+
+## DataLoaderShard
+
+[[autodoc]] data_loader.DataLoaderShard
+
+## DataLoaderDispatcher
+
+[[autodoc]] data_loader.DataLoaderDispatcher
+
+## AcceleratedOptimizer
+
+[[autodoc]] optimizer.AcceleratedOptimizer
+
+## AcceleratedScheduler
+
+[[autodoc]] scheduler.AcceleratedScheduler
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/tracking.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/tracking.md
new file mode 100644
index 0000000000000000000000000000000000000000..8a50cea991386241f4fc70289dd192903cec26b9
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/tracking.md
@@ -0,0 +1,60 @@
+
+
+# Experiment Trackers
+
+## GeneralTracker
+
+[[autodoc]] tracking.GeneralTracker
+
+## TensorBoardTracker
+
+[[autodoc]] tracking.TensorBoardTracker
+ - __init__
+
+## WandBTracker
+
+[[autodoc]] tracking.WandBTracker
+ - __init__
+
+## Trackio
+
+[[autodoc]] tracking.TrackioTracker
+ - __init__
+
+## CometMLTracker
+
+[[autodoc]] tracking.CometMLTracker
+ - __init__
+
+## AimTracker
+
+[[autodoc]] tracking.AimTracker
+ - __init__
+
+## MLflowTracker
+
+[[autodoc]] tracking.MLflowTracker
+ - __init__
+
+## ClearMLTracker
+
+[[autodoc]] tracking.ClearMLTracker
+ - __init__
+
+## SwanLabTracker
+
+[[autodoc]] tracking.SwanLabTracker
+ - __init__
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/utilities.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/utilities.md
new file mode 100644
index 0000000000000000000000000000000000000000..454b6a6bd9b80229a25b8bb9dadb35103a2e8688
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/package_reference/utilities.md
@@ -0,0 +1,253 @@
+
+
+# Utility functions and classes
+
+Below are a variety of utility functions that 🤗 Accelerate provides, broken down by use-case.
+
+## Constants
+
+Constants used throughout 🤗 Accelerate for reference
+
+The following are constants used when utilizing [`Accelerator.save_state`]
+
+`utils.MODEL_NAME`: `"pytorch_model"`
+`utils.OPTIMIZER_NAME`: `"optimizer"`
+`utils.RNG_STATE_NAME`: `"random_states"`
+`utils.SCALER_NAME`: `"scaler.pt`
+`utils.SCHEDULER_NAME`: `"scheduler`
+
+The following are constants used when utilizing [`Accelerator.save_model`]
+
+`utils.WEIGHTS_NAME`: `"pytorch_model.bin"`
+`utils.SAFE_WEIGHTS_NAME`: `"model.safetensors"`
+`utils.WEIGHTS_INDEX_NAME`: `"pytorch_model.bin.index.json"`
+`utils.SAFE_WEIGHTS_INDEX_NAME`: `"model.safetensors.index.json"`
+
+## Data Classes
+
+These are basic dataclasses used throughout 🤗 Accelerate and they can be passed in as parameters.
+
+### Standalone
+
+These are standalone dataclasses used for checks, such as the type of distributed system being used
+
+[[autodoc]] utils.ComputeEnvironment
+
+[[autodoc]] utils.DistributedType
+
+[[autodoc]] utils.DynamoBackend
+
+[[autodoc]] utils.LoggerType
+
+[[autodoc]] utils.PrecisionType
+
+[[autodoc]] utils.RNGType
+
+[[autodoc]] utils.SageMakerDistributedType
+
+### Kwargs
+
+These are configurable arguments for specific interactions throughout the PyTorch ecosystem that Accelerate handles under the hood.
+
+[[autodoc]] utils.AutocastKwargs
+
+[[autodoc]] utils.DistributedDataParallelKwargs
+
+[[autodoc]] utils.FP8RecipeKwargs
+
+[[autodoc]] utils.GradScalerKwargs
+
+[[autodoc]] utils.InitProcessGroupKwargs
+
+[[autodoc]] utils.KwargsHandler
+
+## Plugins
+
+These are plugins that can be passed to the [`Accelerator`] object. While they are defined elsewhere in the documentation,
+for convenience all of them are available to see here:
+
+[[autodoc]] utils.DeepSpeedPlugin
+
+[[autodoc]] utils.FullyShardedDataParallelPlugin
+
+[[autodoc]] utils.GradientAccumulationPlugin
+
+[[autodoc]] utils.MegatronLMPlugin
+
+[[autodoc]] utils.TorchDynamoPlugin
+
+## Configurations
+
+These are classes which can be configured and passed through to the appropriate integration
+
+[[autodoc]] utils.BnbQuantizationConfig
+
+[[autodoc]] utils.DataLoaderConfiguration
+
+[[autodoc]] utils.ProjectConfiguration
+
+## Environmental Variables
+
+These are environmental variables that can be enabled for different use cases
+
+* `ACCELERATE_DEBUG_MODE` (`str`): Whether to run accelerate in debug mode. More info available [here](../usage_guides/debug.md).
+
+
+
+
+## Data Manipulation and Operations
+
+These include data operations that mimic the same `torch` ops but can be used on distributed processes.
+
+[[autodoc]] utils.broadcast
+
+[[autodoc]] utils.broadcast_object_list
+
+[[autodoc]] utils.concatenate
+
+[[autodoc]] utils.convert_outputs_to_fp32
+
+[[autodoc]] utils.convert_to_fp32
+
+[[autodoc]] utils.gather
+
+[[autodoc]] utils.gather_object
+
+[[autodoc]] utils.get_grad_scaler
+
+[[autodoc]] utils.get_mixed_precision_context_manager
+
+[[autodoc]] utils.listify
+
+[[autodoc]] utils.pad_across_processes
+
+[[autodoc]] utils.recursively_apply
+
+[[autodoc]] utils.reduce
+
+[[autodoc]] utils.send_to_device
+
+[[autodoc]] utils.slice_tensors
+
+## Environment Checks
+
+These functionalities check the state of the current working environment including information about the operating system itself, what it can support, and if particular dependencies are installed.
+
+[[autodoc]] utils.is_bf16_available
+
+[[autodoc]] utils.is_ipex_available
+
+[[autodoc]] utils.is_mps_available
+
+[[autodoc]] utils.is_npu_available
+
+[[autodoc]] utils.is_torch_version
+
+[[autodoc]] utils.is_torch_xla_available
+
+[[autodoc]] utils.is_xpu_available
+
+## Environment Manipulation
+
+[[autodoc]] utils.patch_environment
+
+[[autodoc]] utils.clear_environment
+
+[[autodoc]] utils.write_basic_config
+
+When setting up 🤗 Accelerate for the first time, rather than running `accelerate config` [~utils.write_basic_config] can be used as an alternative for quick configuration.
+
+[[autodoc]] utils.set_numa_affinity
+
+[[autodoc]] utils.environment.override_numa_affinity
+
+[[autodoc]] utils.purge_accelerate_environment
+
+## Memory
+
+[[autodoc]] utils.find_executable_batch_size
+
+## Modeling
+
+These utilities relate to interacting with PyTorch models
+
+[[autodoc]] utils.calculate_maximum_sizes
+
+[[autodoc]] utils.compute_module_sizes
+
+[[autodoc]] utils.extract_model_from_parallel
+
+[[autodoc]] utils.get_balanced_memory
+
+[[autodoc]] utils.get_max_layer_size
+
+[[autodoc]] utils.infer_auto_device_map
+
+[[autodoc]] utils.load_checkpoint_in_model
+
+[[autodoc]] utils.load_offloaded_weights
+
+[[autodoc]] utils.load_state_dict
+
+[[autodoc]] utils.offload_state_dict
+
+[[autodoc]] utils.retie_parameters
+
+[[autodoc]] utils.set_module_tensor_to_device
+
+[[autodoc]] utils.get_module_children_bottom_up
+
+## Parallel
+
+These include general utilities that should be used when working in parallel.
+
+[[autodoc]] utils.extract_model_from_parallel
+
+[[autodoc]] utils.save
+
+[[autodoc]] utils.load
+
+[[autodoc]] utils.wait_for_everyone
+
+
+## Random
+
+These utilities relate to setting and synchronizing of all the random states.
+
+[[autodoc]] utils.set_seed
+
+[[autodoc]] utils.synchronize_rng_state
+
+[[autodoc]] utils.synchronize_rng_states
+
+
+## PyTorch XLA
+
+These include utilities that are useful while using PyTorch with XLA.
+
+[[autodoc]] utils.install_xla
+
+## Loading model weights
+
+These include utilities that are useful to load checkpoints.
+
+[[autodoc]] utils.load_checkpoint_in_model
+
+## Quantization
+
+These include utilities that are useful to quantize model.
+
+[[autodoc]] utils.load_and_quantize_model
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/quicktour.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/quicktour.md
new file mode 100644
index 0000000000000000000000000000000000000000..6b21f2e1e083cd2455470004b789d572216e873c
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/quicktour.md
@@ -0,0 +1,189 @@
+
+
+# Quicktour
+
+There are many ways to launch and run your code depending on your training environment ([torchrun](https://pytorch.org/docs/stable/elastic/run.html), [DeepSpeed](https://www.deepspeed.ai/), etc.) and available hardware. Accelerate offers a unified interface for launching and training on different distributed setups, allowing you to focus on your PyTorch training code instead of the intricacies of adapting your code to these different setups. This allows you to easily scale your PyTorch code for training and inference on distributed setups with hardware like GPUs and TPUs. Accelerate also provides Big Model Inference to make loading and running inference with really large models that usually don't fit in memory more accessible.
+
+This quicktour introduces the three main features of Accelerate:
+
+* a unified command line launching interface for distributed training scripts
+* a training library for adapting PyTorch training code to run on different distributed setups
+* Big Model Inference
+
+## Unified launch interface
+
+Accelerate automatically selects the appropriate configuration values for any given distributed training framework (DeepSpeed, FSDP, etc.) through a unified configuration file generated from the [`accelerate config`](package_reference/cli#accelerate-config) command. You could also pass the configuration values explicitly to the command line which is helpful in certain situations like if you're using SLURM.
+
+
+But in most cases, you should always run [`accelerate config`](package_reference/cli#accelerate-config) first to help Accelerate learn about your training setup.
+
+```bash
+accelerate config
+```
+
+The [`accelerate config`](package_reference/cli#accelerate-config) command creates and saves a default_config.yaml file in Accelerates cache folder. This file stores the configuration for your training environment, which helps Accelerate correctly launch your training script based on your machine.
+
+After you've configured your environment, you can test your setup with [`accelerate test`](package_reference/cli#accelerate-test), which launches a short script to test the distributed environment.
+
+```bash
+accelerate test
+```
+
+> [!TIP]
+> Add `--config_file` to the `accelerate test` or `accelerate launch` command to specify the location of the configuration file if it is saved in a non-default location like the cache.
+
+Once your environment is setup, launch your training script with [`accelerate launch`](package_reference/cli#accelerate-launch)!
+
+```bash
+accelerate launch path_to_script.py --args_for_the_script
+```
+
+To learn more, check out the [Launch distributed code](basic_tutorials/launch) tutorial for more information about launching your scripts.
+
+We also have a [configuration zoo](https://github.com/huggingface/accelerate/blob/main/examples/config_yaml_templates) which showcases a number of premade **minimal** example configurations for a variety of setups you can run.
+
+## Adapt training code
+
+The next main feature of Accelerate is the [`Accelerator`] class which adapts your PyTorch code to run on different distributed setups.
+
+You only need to add a few lines of code to your training script to enable it to run on multiple GPUs or TPUs.
+
+```diff
++ from accelerate import Accelerator
++ accelerator = Accelerator()
+
++ device = accelerator.device
++ model, optimizer, training_dataloader, scheduler = accelerator.prepare(
++ model, optimizer, training_dataloader, scheduler
++ )
+
+ for batch in training_dataloader:
+ optimizer.zero_grad()
+ inputs, targets = batch
+- inputs = inputs.to(device)
+- targets = targets.to(device)
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets)
++ accelerator.backward(loss)
+ optimizer.step()
+ scheduler.step()
+```
+
+1. Import and instantiate the [`Accelerator`] class at the beginning of your training script. The [`Accelerator`] class initializes everything necessary for distributed training, and it automatically detects your training environment (a single machine with a GPU, a machine with several GPUs, several machines with multiple GPUs or a TPU, etc.) based on how the code was launched.
+
+```python
+from accelerate import Accelerator
+
+accelerator = Accelerator()
+```
+
+2. Remove calls like `.cuda()` on your model and input data. The [`Accelerator`] class automatically places these objects on the appropriate device for you.
+
+> [!WARNING]
+> This step is *optional* but it is considered best practice to allow Accelerate to handle device placement. You could also deactivate automatic device placement by passing `device_placement=False` when initializing the [`Accelerator`]. If you want to explicitly place objects on a device with `.to(device)`, make sure you use `accelerator.device` instead. For example, if you create an optimizer before placing a model on `accelerator.device`, training fails on a TPU.
+
+> [!WARNING]
+> Accelerate does not use non-blocking transfers by default for its automatic device placement, which can result in potentially unwanted CUDA synchronizations. You can enable non-blocking transfers by passing a [`~utils.dataclasses.DataLoaderConfiguration`] with `non_blocking=True` set as the `dataloader_config` when initializing the [`Accelerator`]. As usual, non-blocking transfers will only work if the dataloader also has `pin_memory=True` set. Be wary that using non-blocking transfers from GPU to CPU may cause incorrect results if it results in CPU operations being performed on non-ready tensors.
+
+```py
+device = accelerator.device
+```
+
+3. Pass all relevant PyTorch objects for training (optimizer, model, dataloader(s), learning rate scheduler) to the [`~Accelerator.prepare`] method as soon as they're created. This method wraps the model in a container optimized for your distributed setup, uses Accelerates version of the optimizer and scheduler, and creates a sharded version of your dataloader for distribution across GPUs or TPUs.
+
+```python
+model, optimizer, train_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, lr_scheduler
+)
+```
+
+4. Replace `loss.backward()` with [`~Accelerator.backward`] to use the correct `backward()` method for your training setup.
+
+```py
+accelerator.backward(loss)
+```
+
+Read [Accelerate’s internal mechanisms](concept_guides/internal_mechanism) guide to learn more details about how Accelerate adapts your code.
+
+### Distributed evaluation
+
+To perform distributed evaluation, pass your validation dataloader to the [`~Accelerator.prepare`] method:
+
+```python
+validation_dataloader = accelerator.prepare(validation_dataloader)
+```
+
+Each device in your distributed setup only receives a part of the evaluation data, which means you should group your predictions together with the [`~Accelerator.gather_for_metrics`] method. This method requires all tensors to be the same size on each process, so if your tensors have different sizes on each process (for instance when dynamically padding to the maximum length in a batch), you should use the [`~Accelerator.pad_across_processes`] method to pad you tensor to the largest size across processes. Note that the tensors needs to be 1D and that we concatenate the tensors along the first dimension.
+
+```python
+for inputs, targets in validation_dataloader:
+ predictions = model(inputs)
+ # Gather all predictions and targets
+ all_predictions, all_targets = accelerator.gather_for_metrics((predictions, targets))
+ # Example of use with a *Datasets.Metric*
+ metric.add_batch(all_predictions, all_targets)
+```
+
+For more complex cases (e.g. 2D tensors, don't want to concatenate tensors, dict of 3D tensors), you can pass `use_gather_object=True` in `gather_for_metrics`. This will return the list of objects after gathering. Note that using it with GPU tensors is not well supported and inefficient.
+
+> [!TIP]
+> Data at the end of a dataset may be duplicated so the batch can be equally divided among all workers. The [`~Accelerator.gather_for_metrics`] method automatically removes the duplicated data to calculate a more accurate metric.
+
+## Big Model Inference
+
+Accelerate's Big Model Inference has two main features, [`~accelerate.init_empty_weights`] and [`~accelerate.load_checkpoint_and_dispatch`], to load large models for inference that typically don't fit into memory.
+
+> [!TIP]
+> Take a look at the [Handling big models for inference](concept_guides/big_model_inference) guide for a better understanding of how Big Model Inference works under the hood.
+
+### Empty weights initialization
+
+The [`~accelerate.init_empty_weights`] context manager initializes models of any size by creating a *model skeleton* and moving and placing parameters each time they're created to PyTorch's [**meta**](https://pytorch.org/docs/main/meta.html) device. This way, not all weights are immediately loaded and only a small part of the model is loaded into memory at a time.
+
+For example, loading an empty [Mixtral-8x7B](https://huggingface.co/mistralai/Mixtral-8x7B-Instruct-v0.1) model takes significantly less memory than fully loading the models and weights on the CPU.
+
+```py
+from accelerate import init_empty_weights
+from transformers import AutoConfig, AutoModelForCausalLM
+
+config = AutoConfig.from_pretrained("mistralai/Mixtral-8x7B-Instruct-v0.1")
+with init_empty_weights():
+ model = AutoModelForCausalLM.from_config(config)
+```
+
+### Load and dispatch weights
+
+The [`~accelerate.load_checkpoint_and_dispatch`] function loads full or sharded checkpoints into the empty model, and automatically distribute weights across all available devices.
+
+The `device_map` parameter determines where to place each model layer, and specifying `"auto"` places them on the GPU first, then the CPU, and finally the hard drive as memory-mapped tensors if there's still not enough memory. Use the `no_split_module_classes` parameter to indicate which modules shouldn't be split across devices (typically those with a residual connection).
+
+```py
+from accelerate import load_checkpoint_and_dispatch
+
+model_checkpoint = "your-local-model-folder"
+model = load_checkpoint_and_dispatch(
+ model, checkpoint=model_checkpoint, device_map="auto", no_split_module_classes=['Block']
+)
+```
+
+## Next steps
+
+Now that you've been introduced to the main Accelerate features, your next steps could include:
+
+* Check out the [tutorials](basic_tutorials/overview) for a gentle walkthrough of Accelerate. This is especially useful if you're new to distributed training and the library.
+* Dive into the [guides](usage_guides/explore) to see how to use Accelerate for specific use-cases.
+* Deepen your conceptual understanding of how Accelerate works internally by reading the [concept guides](concept_guides/internal_mechanism).
+* Look up classes and commands in the [API reference](package_reference/accelerator) to see what parameters and options are available.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/big_modeling.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/big_modeling.md
new file mode 100644
index 0000000000000000000000000000000000000000..0301a188d52456321ec457448ce1502a735fa2b2
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/big_modeling.md
@@ -0,0 +1,124 @@
+
+
+# Big Model Inference
+
+One of the biggest advancements Accelerate provides is [Big Model Inference](../concept_guides/big_model_inference), which allows you to perform inference with models that don't fully fit on your graphics card.
+
+This tutorial will show you how to use Big Model Inference in Accelerate and the Hugging Face ecosystem.
+
+## Accelerate
+
+A typical workflow for loading a PyTorch model is shown below. `ModelClass` is a model that exceeds the GPU memory of your device (mps or cuda or xpu).
+
+```py
+import torch
+
+my_model = ModelClass(...)
+state_dict = torch.load(checkpoint_file)
+my_model.load_state_dict(state_dict)
+```
+
+With Big Model Inference, the first step is to init an empty skeleton of the model with the `init_empty_weights` context manager. This doesn't require any memory because `my_model` is "parameterless".
+
+```py
+from accelerate import init_empty_weights
+with init_empty_weights():
+ my_model = ModelClass(...)
+```
+
+Next, the weights are loaded into the model for inference.
+
+The [`load_checkpoint_and_dispatch`] method loads a checkpoint inside your empty model and dispatches the weights for each layer across all available devices, starting with the fastest devices (GPU, MPS, XPU, NPU, MLU, SDAA, MUSA) first before moving to the slower ones (CPU and hard drive).
+
+Setting `device_map="auto"` automatically fills all available space on the GPU(s) first, then the CPU, and finally, the hard drive (the absolute slowest option) if there is still not enough memory.
+
+> [!TIP]
+> Refer to the [Designing a device map](../concept_guides/big_model_inference#designing-a-device-map) guide for more details on how to design your own device map.
+
+```py
+from accelerate import load_checkpoint_and_dispatch
+
+model = load_checkpoint_and_dispatch(
+ model, checkpoint=checkpoint_file, device_map="auto"
+)
+```
+
+If there are certain “chunks” of layers that shouldn’t be split, pass them to `no_split_module_classes` (see [here](../concept_guides/big_model_inference#loading-weights) for more details).
+
+A models weights can also be sharded into multiple checkpoints to save memory, such as when the `state_dict` doesn't fit in memory (see [here](../concept_guides/big_model_inference#sharded-checkpoints) for more details).
+
+Now that the model is fully dispatched, you can perform inference.
+
+```py
+input = torch.randn(2,3)
+device_type = next(iter(model.parameters())).device.type
+input = input.to(device_type)
+output = model(input)
+```
+
+Each time an input is passed through a layer, it is sent from the CPU to the GPU (or disk to CPU to GPU), the output is calculated, and the layer is removed from the GPU going back down the line. While this adds some overhead to inference, it enables you to run any size model on your system, as long as the largest layer fits on your GPU.
+
+Multiple GPUs, or "model parallelism", can be utilized but only one GPU will be active at any given moment. This forces the GPU to wait for the previous GPU to send it the output. You should launch your script normally with Python instead of other tools like torchrun and accelerate launch.
+
+> [!TIP]
+> You may also be interested in *pipeline parallelism* which utilizes all available GPUs at once, instead of only having one GPU active at a time. This approach is less flexbile though. For more details, refer to the [Memory-efficient pipeline parallelism](./distributed_inference#memory-efficient-pipeline-parallelism-experimental) guide.
+
+
+
+Take a look at a full example of Big Model Inference below.
+
+```py
+import torch
+from accelerate import init_empty_weights, load_checkpoint_and_dispatch
+
+with init_empty_weights():
+ model = MyModel(...)
+
+model = load_checkpoint_and_dispatch(
+ model, checkpoint=checkpoint_file, device_map="auto"
+)
+
+input = torch.randn(2,3)
+device_type = next(iter(model.parameters())).device.type
+input = input.to(device_type)
+output = model(input)
+```
+
+## Hugging Face ecosystem
+
+Other libraries in the Hugging Face ecosystem, like Transformers or Diffusers, supports Big Model Inference in their [`~transformers.PreTrainedModel.from_pretrained`] constructors.
+
+You just need to add `device_map="auto"` in [`~transformers.PreTrainedModel.from_pretrained`] to enable Big Model Inference.
+
+For example, load Big Sciences T0pp 11 billion parameter model with Big Model Inference.
+
+```py
+from transformers import AutoModelForSeq2SeqLM
+
+model = AutoModelForSeq2SeqLM.from_pretrained("bigscience/T0pp", device_map="auto")
+```
+
+After loading the model, the empty init and smart dispatch steps from before are executed and the model is fully ready to make use of all the resources in your machine. Through these constructors, you can also save more memory by specifying the `torch_dtype` parameter to load a model in a lower precision.
+
+```py
+from transformers import AutoModelForSeq2SeqLM
+
+model = AutoModelForSeq2SeqLM.from_pretrained("bigscience/T0pp", device_map="auto", torch_dtype=torch.float16)
+```
+
+## Next steps
+
+For a more detailed explanation of Big Model Inference, make sure to check out the [conceptual guide](../concept_guides/big_model_inference)!
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/checkpoint.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/checkpoint.md
new file mode 100644
index 0000000000000000000000000000000000000000..9c08a454d0e909ef1f75589356d814c379544a34
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/checkpoint.md
@@ -0,0 +1,96 @@
+
+
+# Checkpointing
+
+When training a PyTorch model with Accelerate, you may often want to save and continue a state of training. Doing so requires
+saving and loading the model, optimizer, RNG generators, and the GradScaler. Inside Accelerate are two convenience functions to achieve this quickly:
+- Use [`~Accelerator.save_state`] for saving everything mentioned above to a folder location
+- Use [`~Accelerator.load_state`] for loading everything stored from an earlier `save_state`
+
+To further customize where and how states are saved through [`~Accelerator.save_state`] the [`~utils.ProjectConfiguration`] class can be used. For example
+if `automatic_checkpoint_naming` is enabled each saved checkpoint will be located then at `Accelerator.project_dir/checkpoints/checkpoint_{checkpoint_number}`.
+
+It should be noted that the expectation is that those states come from the same training script, they should not be from two separate scripts.
+
+- By using [`~Accelerator.register_for_checkpointing`], you can register custom objects to be automatically stored or loaded from the two prior functions,
+so long as the object has a `state_dict` **and** a `load_state_dict` functionality. This could include objects such as a learning rate scheduler.
+
+
+Below is a brief example using checkpointing to save and reload a state during training:
+
+```python
+from accelerate import Accelerator
+import torch
+
+accelerator = Accelerator(project_dir="my/save/path")
+
+my_scheduler = torch.optim.lr_scheduler.StepLR(my_optimizer, step_size=1, gamma=0.99)
+my_model, my_optimizer, my_training_dataloader = accelerator.prepare(my_model, my_optimizer, my_training_dataloader)
+
+# Register the LR scheduler
+accelerator.register_for_checkpointing(my_scheduler)
+
+# Save the starting state
+accelerator.save_state()
+
+device = accelerator.device
+my_model.to(device)
+
+# Perform training
+for epoch in range(num_epochs):
+ for batch in my_training_dataloader:
+ my_optimizer.zero_grad()
+ inputs, targets = batch
+ inputs = inputs.to(device)
+ targets = targets.to(device)
+ outputs = my_model(inputs)
+ loss = my_loss_function(outputs, targets)
+ accelerator.backward(loss)
+ my_optimizer.step()
+ my_scheduler.step()
+
+# Restore the previous state
+accelerator.load_state("my/save/path/checkpointing/checkpoint_0")
+```
+
+## Restoring the state of the DataLoader
+
+After resuming from a checkpoint, it may also be desirable to resume from a particular point in the active `DataLoader` if
+the state was saved during the middle of an epoch. You can use [`~Accelerator.skip_first_batches`] to do so.
+
+```python
+from accelerate import Accelerator
+
+accelerator = Accelerator(project_dir="my/save/path")
+
+train_dataloader = accelerator.prepare(train_dataloader)
+accelerator.load_state("my_state")
+
+# Assume the checkpoint was saved 100 steps into the epoch
+skipped_dataloader = accelerator.skip_first_batches(train_dataloader, 100)
+
+# After the first iteration, go back to `train_dataloader`
+
+# First epoch
+for batch in skipped_dataloader:
+ # Do something
+ pass
+
+# Second epoch
+for batch in train_dataloader:
+ # Do something
+ pass
+```
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/compilation.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/compilation.md
new file mode 100644
index 0000000000000000000000000000000000000000..ac9f58e0832127cfb3dc7dc443a7415a7a192bb7
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/compilation.md
@@ -0,0 +1,76 @@
+# Compilation
+
+## Overview
+
+Pytorch 2.0 introduced `torch.compile`, a powerful feature that makes PyTorch code run faster by JIT-compiling PyTorch code into optimized kernels. Key features of `torch.compile` include:
+
+- **Performance Improvement**: Significantly speeds up model execution by optimizing the computation graph.
+- **Ease of Use**: Requires minimal code changes to implement, making it highly accessible.
+- **Compatibility**: Works seamlessly with existing PyTorch code and models.
+
+When used with Accelerate, `torch.compile` integrates smoothly into distributed training workflows, allowing you to benefit from both distributed execution and compilation optimizations simultaneously.
+
+The first execution of compiled code typically takes longer as it includes the compilation time, but subsequent runs are significantly faster. For optimal performance in different scenarios, `torch.compile` offers various modes like `"default"`, `"reduce-overhead"` (which uses CUDA graphs to further reduce overhead), and `"max-autotune"` (which performs extensive autotuning to find the best kernels for your model).
+
+## Using `torch.compile` with Accelerate
+
+Accelerate provides `TorchDynamoPlugin` for easy and seemless integration of `torch.compile` into your training scripts.
+
+```python
+from accelerate import Accelerator
+from accelerate.utils import TorchDynamoPlugin
+
+# Configure the compilation backend
+dynamo_plugin = TorchDynamoPlugin(
+ backend="inductor", # Options: "inductor", "aot_eager", "aot_nvfuser", etc.
+ mode="default", # Options: "default", "reduce-overhead", "max-autotune"
+ fullgraph=True,
+ dynamic=False
+)
+
+# Initialize accelerator with the plugin
+accelerator = Accelerator(dynamo_plugin=dynamo_plugin)
+# This will apply torch.compile to your model
+model = accelerator.prepare(model)
+```
+
+It is compatible with all other features and plugins of Accelerate, including mixed precision, distributed training (DDP, FSDP, Deepspeed), etc.
+
+## Regional Compilation
+
+Instead of trying to compile the whole model, which usually has a big problem space for optimization. Regional compilation targets repeated blocks of the same class and compiles them sequentially to hit the compiler's cache. For example, in `GPT2LMHeadModel`, the repeated block/class is `GPT2Block`, and can be accessed as `model.transformer.h[0]`. The rest of the model (e.g model.lm_head) is compiled separately.
+
+This allows us to speed up the compilation overhead / cold start of models like LLMs and Transformers in general.
+See for more details.
+
+### How to Use Regional Compilation
+
+It can be enabled by setting `use_regional_compilation=True` in the `TorchDynamoPlugin` configuration:
+
+```python
+# Configure the compilation backend
+dynamo_plugin = TorchDynamoPlugin(
+ use_regional_compilation=True,
+ ... # other parameters
+)
+# Initialize accelerator with the plugin
+accelerator = Accelerator(dynamo_plugin=dynamo_plugin)
+# This will apply compile_regions to your model
+model = accelerator.prepare(model)
+```
+
+You could also use the `accelerate.utils.compile_regions` utility directly the same way you would use `torch.compile`.
+
+### Benefits of Regional Compilation
+
+We have conducted extensive benchmarks comparing full compilation and regional compilation using the `torch.compile` feature in PyTorch. The full results are available in the [accelerate repository](https://github.com/huggingface/accelerate/tree/main/benchmarks/torch.compile/regional_compilation). The key findings from our benchmarks are:
+
+1. **Comparable Performance**: Regional compilation delivers performance speedups similar to full compilation, especially for larger models.
+2. **Faster Compilation**: Regional compilation significantly reduces the time taken to compile models, making it a more efficient choice for deployment.
+3. **Batch Size Impact**: The performance difference between compilation strategies diminishes with larger batch sizes, indicating that the overhead of compilation is less impactful in those scenarios.
+4. **Model Size Consideration**: The benefits of regional compilation are more pronounced in larger models, where the compilation time savings can be substantial.
+5. **Practical Application**: For real-world applications, regional compilation is a practical choice for optimizing training cold start times, especially when working with large models.
+
+## Conclusion
+
+Both full and regional compilation can significantly speed up your models. Regional compilation offers a practical balance between compilation time and runtime performance, especially for training large models with substantial batch sizes.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/ddp_comm_hook.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/ddp_comm_hook.md
new file mode 100644
index 0000000000000000000000000000000000000000..252b618be464d591c19fa4205c68c534eb38bd4e
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/ddp_comm_hook.md
@@ -0,0 +1,337 @@
+
+
+# DDP Communication Hooks
+
+Distributed Data Parallel (DDP) communication hooks provide a generic interface to control how gradients are communicated across workers by overriding the vanilla allreduce in `DistributedDataParallel`. A few built-in communication hooks are provided, and users can easily apply any of these hooks to optimize communication.
+
+
+- **FP16 Compression Hook**: Compresses gradients by casting them to half-precision floating-point format (`torch.float16`), reducing communication overhead.
+- **BF16 Compression Hook**: Similar to FP16, but uses the Brain Floating Point format (`torch.bfloat16`), which can be more efficient on certain hardware.
+- **PowerSGD Hook**: An advanced gradient compression algorithm that provides high compression rates and can accelerate bandwidth-bound distributed training.
+
+In this tutorial, you will see how to quickly set up DDP communication hooks and perform training with the utilities provided in Accelerate, which can be as simple as adding just one new line of code! This demonstrates how to use DDP communication hooks to optimize gradient communication in distributed training with the Accelerate library.
+
+## FP16 Compression Hook
+
+
+
+
+```python
+import torch
+from torch.nn.parallel import DistributedDataParallel as DDP
+from torch.distributed.algorithms.ddp_comm_hooks import default_hooks
+from accelerate.test_utils.testing import get_backend
+
+device_type, _, _ = get_backend()
+device_id = getattr(torch, device_type, torch.cuda).current_device()
+
+class MyModel(torch.nn.Module):
+ def __init__(self):
+ super().__init__()
+ self.layer = torch.nn.Linear(10, 10)
+
+ def forward(self, x):
+ return self.layer(x)
+
+model = MyModel()
+model = DDP(model, device_ids=[device_id])
+model.register_comm_hook(state=None, hook=default_hooks.fp16_compress_hook)
+
+# Training loop
+for data, targets in data_loader:
+ outputs = model(data)
+ loss = criterion(outputs, targets)
+ loss.backward()
+ optimizer.step()
+ optimizer.zero_grad()
+```
+
+
+
+
+```python
+from accelerate import Accelerator, DDPCommunicationHookType, DistributedDataParallelKwargs
+import torch
+
+class MyModel(torch.nn.Module):
+ def __init__(self):
+ super().__init__()
+ self.layer = torch.nn.Linear(10, 10)
+
+ def forward(self, x):
+ return self.layer(x)
+
+# DDP Communication Hook setup
+ddp_kwargs = DistributedDataParallelKwargs(comm_hook=DDPCommunicationHookType.FP16)
+accelerator = Accelerator(kwargs_handlers=[ddp_kwargs])
+
+model = MyModel()
+optimizer = torch.optim.Adam(model.parameters())
+data_loader = DataLoader(dataset, batch_size=16)
+
+model, optimizer, data_loader = accelerator.prepare(model, optimizer, data_loader)
+
+# Training loop
+for data, targets in data_loader:
+ outputs = model(data)
+ loss = criterion(outputs, targets)
+ accelerator.backward(loss)
+ optimizer.step()
+ optimizer.zero_grad()
+```
+
+
+
+
+### BF16 Compression Hook
+
+
+
+BF16 Compression Hook API is experimental, and it requires NCCL version later than 2.9.6.
+
+
+
+
+
+
+```python
+import torch
+from torch.nn.parallel import DistributedDataParallel as DDP
+from torch.distributed.algorithms.ddp_comm_hooks import default_hooks
+from accelerate.test_utils.testing import get_backend
+
+device_type, _, _ = get_backend()
+device_id = getattr(torch, device_type, torch.cuda).current_device()
+
+class MyModel(torch.nn.Module):
+ def __init__(self):
+ super().__init__()
+ self.layer = torch.nn.Linear(10, 10)
+
+ def forward(self, x):
+ return self.layer(x)
+
+model = MyModel()
+model = DDP(model, device_ids=[device_id])
+model.register_comm_hook(state=None, hook=default_hooks.bf16_compress_hook)
+
+# Training loop
+for data, targets in data_loader:
+ outputs = model(data)
+ loss = criterion(outputs, targets)
+ loss.backward()
+ optimizer.step()
+ optimizer.zero_grad()
+```
+
+
+
+
+```python
+from accelerate import Accelerator, DDPCommunicationHookType, DistributedDataParallelKwargs
+import torch
+
+class MyModel(torch.nn.Module):
+ def __init__(self):
+ super().__init__()
+ self.layer = torch.nn.Linear(10, 10)
+
+ def forward(self, x):
+ return self.layer(x)
+
+# DDP Communication Hook setup
+ddp_kwargs = DistributedDataParallelKwargs(comm_hook=DDPCommunicationHookType.BF16)
+accelerator = Accelerator(kwargs_handlers=[ddp_kwargs])
+
+model = MyModel()
+optimizer = torch.optim.Adam(model.parameters())
+data_loader = DataLoader(dataset, batch_size=16)
+
+model, optimizer, data_loader = accelerator.prepare(model, optimizer, data_loader)
+
+# Training loop
+for data, targets in data_loader:
+ outputs = model(data)
+ loss = criterion(outputs, targets)
+ accelerator.backward(loss)
+ optimizer.step()
+ optimizer.zero_grad()
+```
+
+
+
+
+### PowerSGD Hook
+
+
+
+PowerSGD typically requires extra memory of the same size as the model’s gradients to enable error feedback, which can compensate for biased compressed communication and improve accuracy.
+
+
+
+
+
+
+```python
+import torch
+from torch.nn.parallel import DistributedDataParallel as DDP
+from torch.distributed.algorithms.ddp_comm_hooks import powerSGD_hook
+from accelerate.test_utils.testing import get_backend
+
+device_type, _, _ = get_backend()
+device_id = getattr(torch, device_type, torch.cuda).current_device()
+
+class MyModel(torch.nn.Module):
+ def __init__(self):
+ super().__init__()
+ self.layer = torch.nn.Linear(10, 10)
+
+ def forward(self, x):
+ return self.layer(x)
+
+model = MyModel()
+model = DDP(model, device_ids=[device_id])
+state = powerSGD_hook.PowerSGDState(process_group=None)
+model.register_comm_hook(state=state, hook=powerSGD_hook.powerSGD_hook)
+
+# Training loop
+for data, targets in data_loader:
+ outputs = model(data)
+ loss = criterion(outputs, targets)
+ loss.backward()
+ optimizer.step()
+ optimizer.zero_grad()
+```
+
+
+
+
+```python
+from accelerate import Accelerator, DDPCommunicationHookType, DistributedDataParallelKwargs
+import torch
+
+class MyModel(torch.nn.Module):
+ def __init__(self):
+ super().__init__()
+ self.layer = torch.nn.Linear(10, 10)
+
+ def forward(self, x):
+ return self.layer(x)
+
+# DDP Communication Hook setup
+ddp_kwargs = DistributedDataParallelKwargs(comm_hook=DDPCommunicationHookType.POWER_SGD)
+accelerator = Accelerator(kwargs_handlers=[ddp_kwargs])
+
+model = MyModel()
+optimizer = torch.optim.Adam(model.parameters())
+data_loader = DataLoader(dataset, batch_size=16)
+
+model, optimizer, data_loader = accelerator.prepare(model, optimizer, data_loader)
+
+# Training loop
+for data, targets in data_loader:
+ outputs = model(data)
+ loss = criterion(outputs, targets)
+ accelerator.backward(loss)
+ optimizer.step()
+ optimizer.zero_grad()
+```
+
+
+
+
+## DDP Communication Hooks utilities
+
+There are two additional utilities for supporting optional functionalities with the communication hooks.
+
+### comm_wrapper
+
+`comm_wrapper` is an option to wrap a communication hook with additional functionality. For example, it can be used to combine FP16 compression with other communication strategies. Currently supported wrappers are `no`, `fp16`, and `bf16`.
+
+```python
+from accelerate import Accelerator, DDPCommunicationHookType, DistributedDataParallelKwargs
+import torch
+
+class MyModel(torch.nn.Module):
+ def __init__(self):
+ super().__init__()
+ self.layer = torch.nn.Linear(10, 10)
+
+ def forward(self, x):
+ return self.layer(x)
+
+# DDP Communication Hook setup
+ddp_kwargs = DistributedDataParallelKwargs(
+ comm_hook=DDPCommunicationHookType.POWER_SGD,
+ comm_wrapper=DDPCommunicationHookType.FP16
+)
+accelerator = Accelerator(kwargs_handlers=[ddp_kwargs])
+
+model = MyModel()
+optimizer = torch.optim.Adam(model.parameters())
+data_loader = DataLoader(dataset, batch_size=16)
+
+model, optimizer, data_loader = accelerator.prepare(model, optimizer, data_loader)
+
+# Training loop
+for data, targets in data_loader:
+ outputs = model(data)
+ loss = criterion(outputs, targets)
+ accelerator.backward(loss)
+ optimizer.step()
+ optimizer.zero_grad()
+```
+
+### comm_state_option
+
+`comm_state_option` allows you to pass additional state information required by certain communication hooks. This is particularly useful for stateful hooks like `PowerSGD`, which require maintaining hyperparameters and internal states across training steps. Below is an example showcasing the use of `comm_state_option` with the `PowerSGD` hook.
+
+```python
+from accelerate import Accelerator, DDPCommunicationHookType, DistributedDataParallelKwargs
+import torch
+
+class MyModel(torch.nn.Module):
+ def __init__(self):
+ super().__init__()
+ self.layer = torch.nn.Linear(10, 10)
+
+ def forward(self, x):
+ return self.layer(x)
+
+# DDP Communication Hook setup
+ddp_kwargs = DistributedDataParallelKwargs(
+ comm_hook=DDPCommunicationHookType.POWER_SGD,
+ comm_state_option={"matrix_approximation_rank": 2}
+)
+accelerator = Accelerator(kwargs_handlers=[ddp_kwargs])
+
+model = MyModel()
+optimizer = torch.optim.Adam(model.parameters())
+data_loader = DataLoader(dataset, batch_size=16)
+
+model, optimizer, data_loader = accelerator.prepare(model, optimizer, data_loader)
+
+# Training loop
+for data, targets in data_loader:
+ outputs = model(data)
+ loss = criterion(outputs, targets)
+ accelerator.backward(loss)
+ optimizer.step()
+ optimizer.zero_grad()
+```
+
+For more advanced usage and additional hooks, refer to the [PyTorch DDP Communication Hooks documentation](https://pytorch.org/docs/stable/ddp_comm_hooks.html).
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/deepspeed.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/deepspeed.md
new file mode 100644
index 0000000000000000000000000000000000000000..8dada66220c7a31f1697c5c300615f61d105c718
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/deepspeed.md
@@ -0,0 +1,745 @@
+
+
+# DeepSpeed
+
+[DeepSpeed](https://github.com/deepspeedai/DeepSpeed) implements everything described in the [ZeRO paper](https://huggingface.co/papers/1910.02054). Some of the salient optimizations are:
+
+1. Optimizer state partitioning (ZeRO stage 1)
+2. Gradient partitioning (ZeRO stage 2)
+3. Parameter partitioning (ZeRO stage 3)
+4. Custom mixed precision training handling
+5. A range of fast CUDA-extension-based optimizers
+6. ZeRO-Offload to CPU and Disk/NVMe
+7. Hierarchical partitioning of model parameters (ZeRO++)
+
+ZeRO-Offload has its own dedicated paper: [ZeRO-Offload: Democratizing Billion-Scale Model Training](https://huggingface.co/papers/2101.06840). And NVMe-support is described in the paper [ZeRO-Infinity: Breaking the GPU
+Memory Wall for Extreme Scale Deep Learning](https://huggingface.co/papers/2104.07857).
+
+DeepSpeed ZeRO-2 is primarily used only for training, as its features are of no use to inference.
+
+DeepSpeed ZeRO-3 can be used for inference as well since it allows huge models to be loaded on multiple GPUs, which
+won't be possible on a single GPU.
+
+Accelerate integrates [DeepSpeed](https://github.com/deepspeedai/DeepSpeed) via 2 options:
+
+1. Integration of the DeepSpeed features via `deepspeed config file` specification in `accelerate config` . You just supply your custom config file or use our template. Most of
+ this document is focused on this feature. This supports all the core features of DeepSpeed and gives user a lot of flexibility.
+ User may have to change a few lines of code depending on the config.
+2. Integration via `deepspeed_plugin`.This supports subset of the DeepSpeed features and uses default options for the rest of the configurations.
+ User need not change any code and is good for those who are fine with most of the default settings of DeepSpeed.
+
+## What is integrated?
+
+Training:
+
+1. Accelerate integrates all features of DeepSpeed ZeRO. This includes all the ZeRO stages 1, 2 and 3 as well as ZeRO-Offload, ZeRO-Infinity (which can offload to disk/NVMe) and ZeRO++.
+Below is a short description of Data Parallelism using ZeRO - Zero Redundancy Optimizer along with diagram from this [blog post](https://www.microsoft.com/en-us/research/blog/zero-deepspeed-new-system-optimizations-enable-training-models-with-over-100-billion-parameters/)
+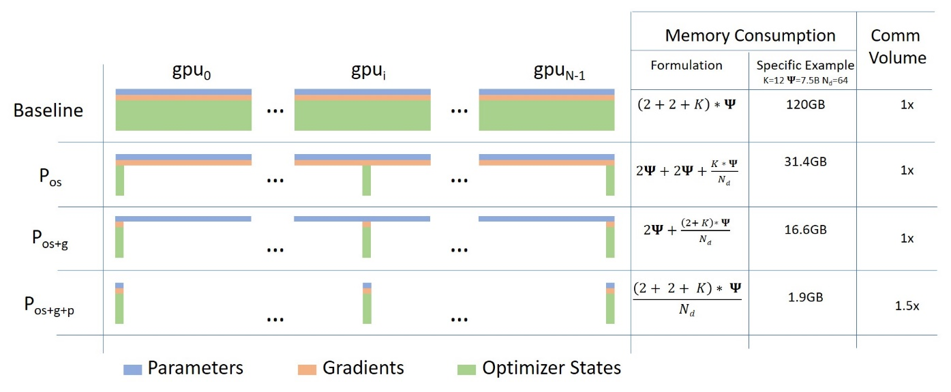
+
+(Source: [link](https://www.microsoft.com/en-us/research/blog/zero-deepspeed-new-system-optimizations-enable-training-models-with-over-100-billion-parameters/))
+
+ a. **Stage 1** : Shards optimizer states across data parallel workers/GPUs
+
+ b. **Stage 2** : Shards optimizer states + gradients across data parallel workers/GPUs
+
+ c. **Stage 3**: Shards optimizer states + gradients + model parameters across data parallel workers/GPUs
+
+ d. **Optimizer Offload**: Offloads the gradients + optimizer states to CPU/Disk building on top of ZERO Stage 2
+
+ e. **Param Offload**: Offloads the model parameters to CPU/Disk building on top of ZERO Stage 3
+
+ f. **Hierarchical Partitioning**: Enables efficient multi-node training with data-parallel training across nodes and ZeRO-3 sharding within a node, built on top of ZeRO Stage 3.
+
+Note: With respect to Disk Offload, the disk should be an NVME for decent speed but it technically works on any Disk
+
+Inference:
+
+1. DeepSpeed ZeRO Inference supports ZeRO stage 3 with ZeRO-Infinity. It uses the same ZeRO protocol as training, but
+ it doesn't use an optimizer and a lr scheduler and only stage 3 is relevant. For more details see:
+ [deepspeed-zero-inference](#deepspeed-zero-inference).
+
+
+## How it works?
+
+**Pre-Requisites**: Install DeepSpeed version >=0.6.5. Please refer to the [DeepSpeed Installation details](https://github.com/deepspeedai/DeepSpeed#installation)
+for more information.
+
+We will first look at easy to use integration via `accelerate config`.
+Followed by more flexible and feature rich `deepspeed config file` integration.
+
+### Accelerate DeepSpeed Plugin
+On your machine(s) just run:
+
+```bash
+accelerate config
+```
+
+and answer the questions asked. It will ask whether you want to use a config file for DeepSpeed to which you should answer no. Then answer the following questions to generate a basic DeepSpeed config.
+This will generate a config file that will be used automatically to properly set the
+default options when doing
+
+```bash
+accelerate launch my_script.py --args_to_my_script
+```
+
+For instance, here is how you would run the NLP example `examples/nlp_example.py` (from the root of the repo) with DeepSpeed Plugin:
+
+**ZeRO Stage-2 DeepSpeed Plugin Example**
+```bash
+compute_environment: LOCAL_MACHINE
+deepspeed_config:
+ gradient_accumulation_steps: 1
+ gradient_clipping: 1.0
+ offload_optimizer_device: none
+ offload_param_device: none
+ zero3_init_flag: true
+ zero_stage: 2
+distributed_type: DEEPSPEED
+fsdp_config: {}
+machine_rank: 0
+main_process_ip: null
+main_process_port: null
+main_training_function: main
+mixed_precision: fp16
+num_machines: 1
+num_processes: 2
+use_cpu: false
+```
+
+```bash
+accelerate launch examples/nlp_example.py --mixed_precision fp16
+```
+
+**ZeRO Stage-3 with CPU Offload DeepSpeed Plugin Example**
+```bash
+compute_environment: LOCAL_MACHINE
+deepspeed_config:
+ gradient_accumulation_steps: 1
+ gradient_clipping: 1.0
+ offload_optimizer_device: cpu
+ offload_param_device: cpu
+ zero3_init_flag: true
+ zero3_save_16bit_model: true
+ zero_stage: 3
+distributed_type: DEEPSPEED
+fsdp_config: {}
+machine_rank: 0
+main_process_ip: null
+main_process_port: null
+main_training_function: main
+mixed_precision: fp16
+num_machines: 1
+num_processes: 2
+use_cpu: false
+```
+
+```bash
+accelerate launch examples/nlp_example.py --mixed_precision fp16
+```
+
+Currently, `Accelerate` supports following config through the CLI:
+
+```bash
+`zero_stage`: [0] Disabled, [1] optimizer state partitioning, [2] optimizer+gradient state partitioning and [3] optimizer+gradient+parameter partitioning
+`gradient_accumulation_steps`: Number of training steps to accumulate gradients before averaging and applying them.
+`gradient_clipping`: Enable gradient clipping with value.
+`offload_optimizer_device`: [none] Disable optimizer offloading, [cpu] offload optimizer to CPU, [nvme] offload optimizer to NVMe SSD. Only applicable with ZeRO >= Stage-2.
+`offload_optimizer_nvme_path`: Decides Nvme Path to offload optimizer states. If unspecified, will default to 'none'.
+`offload_param_device`: [none] Disable parameter offloading, [cpu] offload parameters to CPU, [nvme] offload parameters to NVMe SSD. Only applicable with ZeRO Stage-3.
+`offload_param_nvme_path`: Decides Nvme Path to offload parameters. If unspecified, will default to 'none'.
+`zero3_init_flag`: Decides whether to enable `deepspeed.zero.Init` for constructing massive models. Only applicable with ZeRO Stage-3.
+`zero3_save_16bit_model`: Decides whether to save 16-bit model weights when using ZeRO Stage-3.
+`mixed_precision`: `no` for FP32 training, `fp16` for FP16 mixed-precision training and `bf16` for BF16 mixed-precision training.
+`deepspeed_moe_layer_cls_names`: Comma-separated list of transformer Mixture-of-Experts (MoE) layer class names (case-sensitive) to wrap ,e.g, `MixtralSparseMoeBlock`, `Qwen2MoeSparseMoeBlock`, `JetMoEAttention,JetMoEBlock` ...
+`deepspeed_hostfile`: DeepSpeed hostfile for configuring multi-node compute resources.
+`deepspeed_exclusion_filter`: DeepSpeed exclusion filter string when using mutli-node setup.
+`deepspeed_inclusion_filter`: DeepSpeed inclusion filter string when using mutli-node setup.
+`deepspeed_multinode_launcher`: DeepSpeed multi-node launcher to use, e.g. `pdsh`, `standard`, `openmpi`, `mvapich`, `mpich`, `slurm`, `nossh` (requires DeepSpeed >= 0.14.5). If unspecified, will default to `pdsh`.
+`deepspeed_config_file`: path to the DeepSpeed config file in `json` format. See the next section for more details on this.
+```
+To be able to tweak more options, you will need to use a DeepSpeed config file.
+
+### DeepSpeed Config File
+On your machine(s) just run:
+
+```bash
+accelerate config
+```
+
+and answer the questions asked. It will ask whether you want to use a config file for deepspeed to which you answer yes
+and provide the path to the deepspeed config file.
+This will generate a config file that will be used automatically to properly set the
+default options when doing
+
+```bash
+accelerate launch my_script.py --args_to_my_script
+```
+
+For instance, here is how you would run the NLP example `examples/by_feature/deepspeed_with_config_support.py` (from the root of the repo) with DeepSpeed Config File:
+
+**ZeRO Stage-2 DeepSpeed Config File Example**
+```bash
+compute_environment: LOCAL_MACHINE
+deepspeed_config:
+ deepspeed_config_file: /home/ubuntu/accelerate/examples/deepspeed_config_templates/zero_stage2_config.json
+ zero3_init_flag: true
+distributed_type: DEEPSPEED
+fsdp_config: {}
+machine_rank: 0
+main_process_ip: null
+main_process_port: null
+main_training_function: main
+mixed_precision: fp16
+num_machines: 1
+num_processes: 2
+use_cpu: false
+```
+
+with the contents of `zero_stage2_config.json` being:
+```json
+{
+ "fp16": {
+ "enabled": true,
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ },
+ "optimizer": {
+ "type": "AdamW",
+ "params": {
+ "lr": "auto",
+ "weight_decay": "auto",
+ "torch_adam": true,
+ "adam_w_mode": true
+ }
+ },
+ "scheduler": {
+ "type": "WarmupDecayLR",
+ "params": {
+ "warmup_min_lr": "auto",
+ "warmup_max_lr": "auto",
+ "warmup_num_steps": "auto",
+ "total_num_steps": "auto"
+ }
+ },
+ "zero_optimization": {
+ "stage": 2,
+ "allgather_partitions": true,
+ "allgather_bucket_size": 2e8,
+ "overlap_comm": true,
+ "reduce_scatter": true,
+ "reduce_bucket_size": "auto",
+ "contiguous_gradients": true
+ },
+ "gradient_accumulation_steps": 1,
+ "gradient_clipping": "auto",
+ "steps_per_print": 2000,
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ "wall_clock_breakdown": false
+}
+```
+
+```bash
+accelerate launch examples/by_feature/deepspeed_with_config_support.py \
+--config_name "gpt2-large" \
+--tokenizer_name "gpt2-large" \
+--dataset_name "wikitext" \
+--dataset_config_name "wikitext-2-raw-v1" \
+--block_size 128 \
+--output_dir "./clm/clm_deepspeed_stage2_accelerate" \
+--learning_rate 5e-4 \
+--per_device_train_batch_size 24 \
+--per_device_eval_batch_size 24 \
+--num_train_epochs 3 \
+--with_tracking \
+--report_to "wandb"\
+```
+
+**ZeRO Stage-3 with CPU offload DeepSpeed Config File Example**
+```bash
+compute_environment: LOCAL_MACHINE
+deepspeed_config:
+ deepspeed_config_file: /home/ubuntu/accelerate/examples/deepspeed_config_templates/zero_stage3_offload_config.json
+ zero3_init_flag: true
+distributed_type: DEEPSPEED
+fsdp_config: {}
+machine_rank: 0
+main_process_ip: null
+main_process_port: null
+main_training_function: main
+mixed_precision: fp16
+num_machines: 1
+num_processes: 2
+use_cpu: false
+```
+with the contents of `zero_stage3_offload_config.json` being:
+```json
+{
+ "fp16": {
+ "enabled": true,
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ },
+ "optimizer": {
+ "type": "AdamW",
+ "params": {
+ "lr": "auto",
+ "weight_decay": "auto"
+ }
+ },
+ "scheduler": {
+ "type": "WarmupDecayLR",
+ "params": {
+ "warmup_min_lr": "auto",
+ "warmup_max_lr": "auto",
+ "warmup_num_steps": "auto",
+ "total_num_steps": "auto"
+ }
+ },
+ "zero_optimization": {
+ "stage": 3,
+ "offload_optimizer": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ "offload_param": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ "overlap_comm": true,
+ "contiguous_gradients": true,
+ "reduce_bucket_size": "auto",
+ "stage3_prefetch_bucket_size": "auto",
+ "stage3_param_persistence_threshold": "auto",
+ "sub_group_size": 1e9,
+ "stage3_max_live_parameters": 1e9,
+ "stage3_max_reuse_distance": 1e9,
+ "stage3_gather_16bit_weights_on_model_save": "auto"
+ },
+ "gradient_accumulation_steps": 1,
+ "gradient_clipping": "auto",
+ "steps_per_print": 2000,
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ "wall_clock_breakdown": false
+}
+```
+
+```bash
+accelerate launch examples/by_feature/deepspeed_with_config_support.py \
+--config_name "gpt2-large" \
+--tokenizer_name "gpt2-large" \
+--dataset_name "wikitext" \
+--dataset_config_name "wikitext-2-raw-v1" \
+--block_size 128 \
+--output_dir "./clm/clm_deepspeed_stage3_offload_accelerate" \
+--learning_rate 5e-4 \
+--per_device_train_batch_size 32 \
+--per_device_eval_batch_size 32 \
+--num_train_epochs 3 \
+--with_tracking \
+--report_to "wandb"\
+```
+
+**ZeRO++ Config Example**
+You can use the features of ZeRO++ by using the appropriate config parameters. Note that ZeRO++ is an extension for ZeRO Stage 3. Here is how the config file can be modified, from [DeepSpeed's ZeRO++ tutorial](https://www.deepspeed.ai/tutorials/zeropp/):
+
+```json
+{
+ "zero_optimization": {
+ "stage": 3,
+ "reduce_bucket_size": "auto",
+
+ "zero_quantized_weights": true,
+ "zero_hpz_partition_size": 8,
+ "zero_quantized_gradients": true,
+
+ "contiguous_gradients": true,
+ "overlap_comm": true
+ }
+}
+```
+
+For hierarchical partitioning, the partition size `zero_hpz_partition_size` should ideally be set to the number of GPUs per node. (For example, the above config file assumes 8 GPUs per node)
+
+**Important code changes when using DeepSpeed Config File**
+
+1. DeepSpeed Optimizers and Schedulers. For more information on these,
+see the [DeepSpeed Optimizers](https://deepspeed.readthedocs.io/en/latest/optimizers.html) and [DeepSpeed Schedulers](https://deepspeed.readthedocs.io/en/latest/schedulers.html) documentation.
+We will look at the changes needed in the code when using these.
+
+ a. DS Optim + DS Scheduler: The case when both `optimizer` and `scheduler` keys are present in the DeepSpeed config file.
+ In this situation, those will be used and the user has to use `accelerate.utils.DummyOptim` and `accelerate.utils.DummyScheduler` to replace the PyTorch/Custom optimizers and schedulers in their code.
+ Below is the snippet from `examples/by_feature/deepspeed_with_config_support.py` showing this:
+ ```python
+ # Creates Dummy Optimizer if `optimizer` was specified in the config file else creates Adam Optimizer
+ optimizer_cls = (
+ torch.optim.AdamW
+ if accelerator.state.deepspeed_plugin is None
+ or "optimizer" not in accelerator.state.deepspeed_plugin.deepspeed_config
+ else DummyOptim
+ )
+ optimizer = optimizer_cls(optimizer_grouped_parameters, lr=args.learning_rate)
+
+ # Creates Dummy Scheduler if `scheduler` was specified in the config file else creates `args.lr_scheduler_type` Scheduler
+ if (
+ accelerator.state.deepspeed_plugin is None
+ or "scheduler" not in accelerator.state.deepspeed_plugin.deepspeed_config
+ ):
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps,
+ num_training_steps=args.max_train_steps,
+ )
+ else:
+ lr_scheduler = DummyScheduler(
+ optimizer, total_num_steps=args.max_train_steps, warmup_num_steps=args.num_warmup_steps
+ )
+ ```
+ b. Custom Optim + Custom Scheduler: The case when both `optimizer` and `scheduler` keys are absent in the DeepSpeed config file.
+ In this situation, no code changes are needed from the user and this is the case when using integration via DeepSpeed Plugin.
+ In the above example we can see that the code remains unchanged if the `optimizer` and `scheduler` keys are absent in the DeepSpeed config file.
+
+ c. Custom Optim + DS Scheduler: The case when only `scheduler` key is present in the DeepSpeed config file.
+ In this situation, the user has to use `accelerate.utils.DummyScheduler` to replace the PyTorch/Custom scheduler in their code.
+
+ d. DS Optim + Custom Scheduler: The case when only `optimizer` key is present in the DeepSpeed config file.
+ This will result in an error because you can only use DS Scheduler when using DS Optim.
+
+2. Notice the `auto` values in the above example DeepSpeed config files. These are automatically handled by `prepare` method
+based on model, dataloaders, dummy optimizer and dummy schedulers provided to `prepare` method.
+Only the `auto` fields specified in above examples are handled by `prepare` method and the rest have to be explicitly specified by the user.
+
+The `auto` values are calculated as:
+
+- `reduce_bucket_size`: `hidden_size * hidden_size`
+- `stage3_prefetch_bucket_size`: `int(0.9 * hidden_size * hidden_size)`
+- `stage3_param_persistence_threshold`: `10 * hidden_size`
+
+For the `auto` feature to work for these 3 config entries - Accelerate will use `model.config.hidden_size` or `max(model.config.hidden_sizes)` as `hidden_size`. If neither of these is available, the launching will fail and you will have to set these 3 config entries manually. Remember the first 2 config entries are the communication buffers - the larger they are the more efficient the comms will be, and the larger they are the more GPU memory they will consume, so it's a tunable performance trade-off.
+
+
+**Things to note when using DeepSpeed Config File**
+
+Below is a sample script using `deepspeed_config_file` in different scenarios.
+
+Code `test.py`:
+
+```python
+from accelerate import Accelerator
+from accelerate.state import AcceleratorState
+
+
+def main():
+ accelerator = Accelerator()
+ accelerator.print(f"{AcceleratorState()}")
+
+
+if __name__ == "__main__":
+ main()
+```
+
+**Scenario 1**: Manually tampered accelerate config file having `deepspeed_config_file` along with other entries.
+
+1. Content of the `accelerate` config:
+
+```yaml
+command_file: null
+commands: null
+compute_environment: LOCAL_MACHINE
+deepspeed_config:
+ gradient_accumulation_steps: 1
+ gradient_clipping: 1.0
+ offload_optimizer_device: 'cpu'
+ offload_param_device: 'cpu'
+ zero3_init_flag: true
+ zero3_save_16bit_model: true
+ zero_stage: 3
+ deepspeed_config_file: 'ds_config.json'
+distributed_type: DEEPSPEED
+downcast_bf16: 'no'
+dynamo_backend: 'NO'
+fsdp_config: {}
+gpu_ids: null
+machine_rank: 0
+main_process_ip: null
+main_process_port: null
+main_training_function: main
+megatron_lm_config: {}
+num_machines: 1
+num_processes: 2
+rdzv_backend: static
+same_network: true
+tpu_name: null
+tpu_zone: null
+use_cpu: false
+```
+
+2. `ds_config.json`:
+
+```json
+{
+ "bf16": {
+ "enabled": true
+ },
+ "zero_optimization": {
+ "stage": 3,
+ "stage3_gather_16bit_weights_on_model_save": false,
+ "offload_optimizer": {
+ "device": "none"
+ },
+ "offload_param": {
+ "device": "none"
+ }
+ },
+ "gradient_clipping": 1.0,
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ "gradient_accumulation_steps": 10,
+ "steps_per_print": 2000000
+}
+```
+
+3. Output of `accelerate launch test.py`:
+
+```bash
+ValueError: When using `deepspeed_config_file`, the following accelerate config variables will be ignored:
+['gradient_accumulation_steps', 'gradient_clipping', 'zero_stage', 'offload_optimizer_device', 'offload_param_device',
+'zero3_save_16bit_model', 'mixed_precision'].
+Please specify them appropriately in the DeepSpeed config file.
+If you are using an accelerate config file, remove other config variables mentioned in the above specified list.
+The easiest method is to create a new config following the questionnaire via `accelerate config`.
+It will only ask for the necessary config variables when using `deepspeed_config_file`.
+```
+
+**Scenario 2**: Use the solution of the error to create new accelerate config and check that no ambiguity error is now thrown.
+
+1. Run `accelerate config`:
+
+```bash
+$ accelerate config
+-------------------------------------------------------------------------------------------------------------------------------
+In which compute environment are you running?
+This machine
+-------------------------------------------------------------------------------------------------------------------------------
+Which type of machine are you using?
+multi-GPU
+How many different machines will you use (use more than 1 for multi-node training)? [1]:
+Do you wish to optimize your script with torch dynamo?[yes/NO]:
+Do you want to use DeepSpeed? [yes/NO]: yes
+Do you want to specify a json file to a DeepSpeed config? [yes/NO]: yes
+Please enter the path to the json DeepSpeed config file: ds_config.json
+Do you want to enable `deepspeed.zero.Init` when using ZeRO Stage-3 for constructing massive models? [yes/NO]: yes
+How many GPU(s) should be used for distributed training? [1]:4
+accelerate configuration saved at ds_config_sample.yaml
+```
+
+2. Content of the `accelerate` config:
+
+```yaml
+compute_environment: LOCAL_MACHINE
+deepspeed_config:
+ deepspeed_config_file: ds_config.json
+ zero3_init_flag: true
+distributed_type: DEEPSPEED
+downcast_bf16: 'no'
+dynamo_backend: 'NO'
+fsdp_config: {}
+machine_rank: 0
+main_training_function: main
+megatron_lm_config: {}
+num_machines: 1
+num_processes: 4
+rdzv_backend: static
+same_network: true
+use_cpu: false
+```
+
+3. Output of `accelerate launch test.py`:
+
+```bash
+Distributed environment: DEEPSPEED Backend: nccl
+Num processes: 4
+Process index: 0
+Local process index: 0
+Device: cuda:0
+Mixed precision type: bf16
+ds_config: {'bf16': {'enabled': True}, 'zero_optimization': {'stage': 3, 'stage3_gather_16bit_weights_on_model_save': False, 'offload_optimizer': {'device': 'none'}, 'offload_param': {'device': 'none'}}, 'gradient_clipping': 1.0, 'train_batch_size': 'auto', 'train_micro_batch_size_per_gpu': 'auto', 'gradient_accumulation_steps': 10, 'steps_per_print': inf, 'fp16': {'enabled': False}}
+```
+
+**Scenario 3**: Setting the `accelerate launch` command arguments related to DeepSpeed as `"auto"` in the DeepSpeed` configuration file and check that things work as expected.
+
+1. New `ds_config.json` with `"auto"` for the `accelerate launch` DeepSpeed command arguments:
+
+```json
+{
+ "bf16": {
+ "enabled": "auto"
+ },
+ "zero_optimization": {
+ "stage": "auto",
+ "stage3_gather_16bit_weights_on_model_save": "auto",
+ "offload_optimizer": {
+ "device": "auto"
+ },
+ "offload_param": {
+ "device": "auto"
+ }
+ },
+ "gradient_clipping": "auto",
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ "gradient_accumulation_steps": "auto",
+ "steps_per_print": 2000000
+}
+```
+
+2. Output of `accelerate launch --mixed_precision="fp16" --zero_stage=3 --gradient_accumulation_steps=5 --gradient_clipping=1.0 --offload_param_device="cpu" --offload_optimizer_device="nvme" --zero3_save_16bit_model="true" test.py`:
+
+```bash
+Distributed environment: DEEPSPEED Backend: nccl
+Num processes: 4
+Process index: 0
+Local process index: 0
+Device: cuda:0
+Mixed precision type: fp16
+ds_config: {'bf16': {'enabled': False}, 'zero_optimization': {'stage': 3, 'stage3_gather_16bit_weights_on_model_save': True, 'offload_optimizer': {'device': 'nvme'}, 'offload_param': {'device': 'cpu'}}, 'gradient_clipping': 1.0, 'train_batch_size': 'auto', 'train_micro_batch_size_per_gpu': 'auto', 'gradient_accumulation_steps': 5, 'steps_per_print': inf, 'fp16': {'enabled': True, 'auto_cast': True}}
+```
+
+**Note**:
+1. Remaining `"auto"` values are handled in `accelerator.prepare()` call as explained in point 2 of
+`Important code changes when using DeepSpeed Config File`.
+2. Only when `gradient_accumulation_steps` is `auto`, the value passed while creating `Accelerator` object via `Accelerator(gradient_accumulation_steps=k)` will be used. When using DeepSpeed Plugin, the value from it will be used and it will overwrite the value passed while creating Accelerator object.
+
+## Saving and loading
+
+1. Saving and loading of models is unchanged for ZeRO Stage-1 and Stage-2.
+
+2. under ZeRO Stage-3, `state_dict` contains just the placeholders since the model weights are partitioned across multiple GPUs.
+ZeRO Stage-3 has 2 options:
+
+ a. Saving the entire 16bit model weights to directly load later on using `model.load_state_dict(torch.load(pytorch_model.bin))`.
+ For this, either set `zero_optimization.stage3_gather_16bit_weights_on_model_save` to True in DeepSpeed Config file or set
+ `zero3_save_16bit_model` to True in DeepSpeed Plugin.
+ **Note that this option requires consolidation of the weights on one GPU it can be slow and memory demanding, so only use this feature when needed.**
+ Below is the snippet from `examples/by_feature/deepspeed_with_config_support.py` showing this:
+ ```python
+ unwrapped_model = accelerator.unwrap_model(model)
+
+ # New Code #
+ # Saves the whole/unpartitioned fp16 model when in ZeRO Stage-3 to the output directory if
+ # `stage3_gather_16bit_weights_on_model_save` is True in DeepSpeed Config file or
+ # `zero3_save_16bit_model` is True in DeepSpeed Plugin.
+ # For Zero Stages 1 and 2, models are saved as usual in the output directory.
+ # The model name saved is `pytorch_model.bin`
+ unwrapped_model.save_pretrained(
+ args.output_dir,
+ is_main_process=accelerator.is_main_process,
+ save_function=accelerator.save,
+ state_dict=accelerator.get_state_dict(model),
+ )
+ ```
+
+ b. To get 32bit weights, first save the model using `model.save_checkpoint()`.
+ Below is the snippet from `examples/by_feature/deepspeed_with_config_support.py` showing this:
+ ```python
+ success = model.save_checkpoint(PATH, ckpt_id, checkpoint_state_dict)
+ status_msg = f"checkpointing: PATH={PATH}, ckpt_id={ckpt_id}"
+ if success:
+ logging.info(f"Success {status_msg}")
+ else:
+ logging.warning(f"Failure {status_msg}")
+ ```
+ This will create ZeRO model and optimizer partitions along with `zero_to_fp32.py` script in checkpoint directory.
+ You can use this script to do offline consolidation.
+ It requires no configuration files or GPUs. Here is an example of its usage:
+ ```bash
+ $ cd /path/to/checkpoint_dir
+ $ ./zero_to_fp32.py . pytorch_model.bin
+ Processing zero checkpoint at global_step1
+ Detected checkpoint of type zero stage 3, world_size: 2
+ Saving fp32 state dict to pytorch_model.bin (total_numel=60506624)
+ ```
+ To get 32bit model for saving/inference, you can perform:
+ ```python
+ from deepspeed.utils.zero_to_fp32 import load_state_dict_from_zero_checkpoint
+
+ unwrapped_model = accelerator.unwrap_model(model)
+ fp32_model = load_state_dict_from_zero_checkpoint(unwrapped_model, checkpoint_dir)
+ ```
+ If you are only interested in the `state_dict`, you can do the following:
+ ```python
+ from deepspeed.utils.zero_to_fp32 import get_fp32_state_dict_from_zero_checkpoint
+
+ state_dict = get_fp32_state_dict_from_zero_checkpoint(checkpoint_dir)
+ ```
+ Note that all these functions require ~2x memory (general RAM) of the size of the final checkpoint.
+
+## ZeRO Inference
+DeepSpeed ZeRO Inference supports ZeRO stage 3 with ZeRO-Infinity.
+It uses the same ZeRO protocol as training, but it doesn't use an optimizer and a lr scheduler and only stage 3 is relevant.
+With accelerate integration, you just need to prepare the model and dataloader as shown below:
+
+```python
+model, eval_dataloader = accelerator.prepare(model, eval_dataloader)
+```
+
+## Few caveats to be aware of
+
+1. Current integration doesn’t support Pipeline Parallelism of DeepSpeed.
+2. Current integration doesn’t support `mpu`, limiting the tensor parallelism which is supported in Megatron-LM.
+3. Current integration doesn’t support multiple models.
+
+## Multi-node DeepSpeed
+DeepSpeed supports multi-node inference and training over a variety of different launchers. You can specify a different launcher by setting the `deepspeed_multinode_launcher` config in the CLI or in the DeepSpeed config file.
+
+Currently, accelerate supports passing configuration for the following DeepSpeed multi-node launchers: `pdsh` (default), `standard`, `openmpi`, `mvapich`, `mpich`, `slurm`, `nossh` (requires DeepSpeed >= 0.14.5).
+
+Please read the [DeepSpeed documentation](https://www.deepspeed.ai/getting-started/#resource-configuration-multi-node) for more information on the different launchers. By default, DeepSpeed will attempt to use passwordless SSH from the main machine node to the other nodes to perform the launcher command. In this configuration, the accelerate launch command only needs to be run on the main node. If using the `nossh` launcher, you will need to run the accelerate launch command on every node using copied configuration.
+
+## DeepSpeed Resources
+
+The documentation for the internals related to deepspeed can be found [here](../package_reference/deepspeed).
+
+- [Project's github](https://github.com/deepspeedai/DeepSpeed)
+- [Usage docs](https://www.deepspeed.ai/getting-started/)
+- [API docs](https://deepspeed.readthedocs.io/en/latest/index.html)
+- [Blog posts](https://www.microsoft.com/en-us/research/search/?q=deepspeed)
+
+Papers:
+
+- [ZeRO: Memory Optimizations Toward Training Trillion Parameter Models](https://huggingface.co/papers/1910.02054)
+- [ZeRO-Offload: Democratizing Billion-Scale Model Training](https://huggingface.co/papers/2101.06840)
+- [ZeRO-Infinity: Breaking the GPU Memory Wall for Extreme Scale Deep Learning](https://huggingface.co/papers/2104.07857)
+- [ZeRO++: Extremely Efficient Collective Communication for Giant Model Training](https://huggingface.co/papers/2306.10209)
+
+
+Finally, please, remember that `Accelerate` only integrates DeepSpeed, therefore if you
+have any problems or questions with regards to DeepSpeed usage, please, file an issue with [DeepSpeed GitHub](https://github.com/deepspeedai/DeepSpeed/issues).
+
+
+
+
+ For those interested in the similarities and differences between FSDP and DeepSpeed, please check out the [concept guide here](../concept_guides/fsdp_and_deepspeed)!
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/deepspeed_multiple_model.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/deepspeed_multiple_model.md
new file mode 100644
index 0000000000000000000000000000000000000000..59e813ad2d25c0911ddda3058a9bba01bec1dc2b
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/deepspeed_multiple_model.md
@@ -0,0 +1,246 @@
+
+
+# Using multiple models with DeepSpeed
+
+
+
+ This guide assumes that you have read and understood the [DeepSpeed usage guide](./deepspeed.md).
+
+
+
+Running multiple models with Accelerate and DeepSpeed is useful for:
+
+* Knowledge distillation
+* Post-training techniques like RLHF (see the [TRL](https://github.com/huggingface/trl) library for more examples)
+* Training multiple models at once
+
+Currently, Accelerate has a **very experimental API** to help you use multiple models.
+
+This tutorial will focus on two common use cases:
+
+1. Knowledge distillation, where a smaller student model is trained to mimic a larger, better-performing teacher. If the student model fits on a single GPU, we can use ZeRO-2 for training and ZeRO-3 to shard the teacher for inference. This is significantly faster than using ZeRO-3 for both models.
+2. Training multiple *disjoint* models at once.
+
+## Knowledge distillation
+
+Knowledge distillation is a good example of using multiple models, but only training one of them.
+
+Normally, you would use a single [`utils.DeepSpeedPlugin`] for both models. However, in this case, there are two separate configurations. Accelerate allows you to create and use multiple plugins **if and only if** they are in a `dict` so that you can reference and enable the proper plugin when needed.
+
+```python
+from accelerate.utils import DeepSpeedPlugin
+
+zero2_plugin = DeepSpeedPlugin(hf_ds_config="zero2_config.json")
+zero3_plugin = DeepSpeedPlugin(hf_ds_config="zero3_config.json")
+
+deepspeed_plugins = {"student": zero2_plugin, "teacher": zero3_plugin}
+```
+
+The `zero2_config.json` should be configured for full training (so specify `scheduler` and `optimizer` if you are not utilizing your own), while `zero3_config.json` should only be configured for the inference model, as shown in the example below.
+
+```json
+{
+ "bf16": {
+ "enabled": "auto"
+ },
+ "zero_optimization": {
+ "stage": 3,
+ "overlap_comm": true,
+ "reduce_bucket_size": "auto",
+ "stage3_prefetch_bucket_size": "auto",
+ "stage3_param_persistence_threshold": "auto",
+ "stage3_max_live_parameters": "auto",
+ "stage3_max_reuse_distance": "auto",
+ },
+ "train_micro_batch_size_per_gpu": 1
+}
+```
+
+An example `zero2_config.json` configuration is shown below.
+
+```json
+{
+ "bf16": {
+ "enabled": "auto"
+ },
+ "optimizer": {
+ "type": "AdamW",
+ "params": {
+ "lr": "auto",
+ "weight_decay": "auto",
+ "torch_adam": true,
+ "adam_w_mode": true
+ }
+ },
+ "scheduler": {
+ "type": "WarmupLR",
+ "params": {
+ "warmup_min_lr": "auto",
+ "warmup_max_lr": "auto",
+ "warmup_num_steps": "auto"
+ }
+ },
+ "zero_optimization": {
+ "stage": 2,
+ "offload_optimizer": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ },
+ "gradient_accumulation_steps": 1,
+ "gradient_clipping": "auto",
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+}
+```
+
+
+
+ DeepSpeed will raise an error if `train_micro_batch_size_per_gpu` isn't specified, even if this particular model isn't being trained.
+
+
+
+From here, create a single [`Accelerator`] and pass in both configurations.
+
+```python
+from accelerate import Accelerator
+
+accelerator = Accelerator(deepspeed_plugins=deepspeed_plugins)
+```
+
+Now let's see how to use them.
+
+### Student model
+
+By default, Accelerate sets the first item in the `dict` as the default or enabled plugin (`"student"` plugin). Verify this by using the [`utils.deepspeed.get_active_deepspeed_plugin`] function to see which plugin is enabled.
+
+```python
+active_plugin = get_active_deepspeed_plugin(accelerator.state)
+assert active_plugin is deepspeed_plugins["student"]
+```
+
+[`AcceleratorState`] also keeps the active DeepSpeed plugin saved in `state.deepspeed_plugin`.
+```python
+assert active_plugin is accelerator.deepspeed_plugin
+```
+
+Since `student` is the currently active plugin, let's go ahead and prepare the model, optimizer, and scheduler.
+
+```python
+student_model, optimizer, scheduler = ...
+student_model, optimizer, scheduler, train_dataloader = accelerator.prepare(student_model, optimizer, scheduler, train_dataloader)
+```
+
+Now it's time to deal with the teacher model.
+
+### Teacher model
+
+First, you need to specify in [`Accelerator`] that the `zero3_config.json` configuration should be used.
+
+```python
+accelerator.state.select_deepspeed_plugin("teacher")
+```
+
+This disables the `"student"` plugin and enables the `"teacher"` plugin instead. The
+DeepSpeed stateful config inside of Transformers is updated, and it changes which plugin configuration gets called when using
+`deepspeed.initialize()`. This allows you to use the automatic `deepspeed.zero.Init` context manager integration Transformers provides.
+
+```python
+teacher_model = AutoModel.from_pretrained(...)
+teacher_model = accelerator.prepare(teacher_model)
+```
+
+Otherwise, you should manually initialize the model with `deepspeed.zero.Init`.
+```python
+with deepspeed.zero.Init(accelerator.deepspeed_plugin.config):
+ model = MyModel(...)
+```
+
+### Training
+
+From here, your training loop can be whatever you like, as long as `teacher_model` is never being trained on.
+
+```python
+teacher_model.eval()
+student_model.train()
+for batch in train_dataloader:
+ with torch.no_grad():
+ output_teacher = teacher_model(**batch)
+ output_student = student_model(**batch)
+ # Combine the losses or modify it in some way
+ loss = output_teacher.loss + output_student.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ scheduler.step()
+ optimizer.zero_grad()
+```
+
+## Train multiple disjoint models
+
+Training multiple models is a more complicated scenario.
+In its current state, we assume each model is **completely disjointed** from the other during training.
+
+This scenario still requires two [`utils.DeepSpeedPlugin`]'s to be made. However, you also need a second [`Accelerator`], since different `deepspeed` engines are being called at different times. A single [`Accelerator`] can only carry one instance at a time.
+
+Since the [`state.AcceleratorState`] is a stateful object though, it is already aware of both [`utils.DeepSpeedPlugin`]'s available. You can just instantiate a second [`Accelerator`] with no extra arguments.
+
+```python
+first_accelerator = Accelerator(deepspeed_plugins=deepspeed_plugins)
+second_accelerator = Accelerator()
+```
+
+You can call either `first_accelerator.state.select_deepspeed_plugin()` to enable or disable
+a particular plugin, and then call [`prepare`].
+
+```python
+# can be `accelerator_0`, `accelerator_1`, or by calling `AcceleratorState().select_deepspeed_plugin(...)`
+first_accelerator.state.select_deepspeed_plugin("first_model")
+first_model = AutoModel.from_pretrained(...)
+# For this example, `get_training_items` is a nonexistent function that gets the setup we need for training
+first_optimizer, first_scheduler, train_dl, eval_dl = get_training_items(model1)
+first_model, first_optimizer, first_scheduler, train_dl, eval_dl = accelerator.prepare(
+ first_model, first_optimizer, first_scheduler, train_dl, eval_dl
+)
+
+second_accelerator.state.select_deepspeed_plugin("second_model")
+second_model = AutoModel.from_pretrained(...)
+# For this example, `get_training_items` is a nonexistent function that gets the setup we need for training
+second_optimizer, second_scheduler, _, _ = get_training_items(model2)
+second_model, second_optimizer, second_scheduler = accelerator.prepare(
+ second_model, second_optimizer, second_scheduler
+)
+```
+
+And now you can train:
+
+```python
+for batch in dl:
+ outputs1 = first_model(**batch)
+ first_accelerator.backward(outputs1.loss)
+ first_optimizer.step()
+ first_scheduler.step()
+ first_optimizer.zero_grad()
+
+ outputs2 = model2(**batch)
+ second_accelerator.backward(outputs2.loss)
+ second_optimizer.step()
+ second_scheduler.step()
+ second_optimizer.zero_grad()
+```
+
+## Resources
+
+To see more examples, please check out the [related tests](https://github.com/huggingface/accelerate/blob/main/src/accelerate/test_utils/scripts/external_deps/test_ds_multiple_model.py) currently in [Accelerate].
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/distributed_inference.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/distributed_inference.md
new file mode 100644
index 0000000000000000000000000000000000000000..cc2bae73efe78335ff201cb68bd282d07176f530
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/distributed_inference.md
@@ -0,0 +1,237 @@
+
+
+# Distributed inference
+
+Distributed inference can fall into three brackets:
+
+1. Loading an entire model onto each GPU and sending chunks of a batch through each GPU's model copy at a time
+2. Loading parts of a model onto each GPU and processing a single input at one time
+3. Loading parts of a model onto each GPU and using what is called scheduled Pipeline Parallelism to combine the two prior techniques.
+
+We're going to go through the first and the last bracket, showcasing how to do each as they are more realistic scenarios.
+
+
+## Sending chunks of a batch automatically to each loaded model
+
+This is the most memory-intensive solution, as it requires each GPU to keep a full copy of the model in memory at a given time.
+
+Normally when doing this, users send the model to a specific device to load it from the CPU, and then move each prompt to a different device.
+
+A basic pipeline using the `diffusers` library might look something like so:
+
+```python
+import torch
+import torch.distributed as dist
+from diffusers import DiffusionPipeline
+
+pipe = DiffusionPipeline.from_pretrained("runwayml/stable-diffusion-v1-5", torch_dtype=torch.float16)
+```
+Followed then by performing inference based on the specific prompt:
+
+```python
+def run_inference(rank, world_size):
+ dist.init_process_group("nccl", rank=rank, world_size=world_size)
+ pipe.to(rank)
+
+ if torch.distributed.get_rank() == 0:
+ prompt = "a dog"
+ elif torch.distributed.get_rank() == 1:
+ prompt = "a cat"
+
+ result = pipe(prompt).images[0]
+ result.save(f"result_{rank}.png")
+```
+One will notice how we have to check the rank to know what prompt to send, which can be a bit tedious.
+
+A user might then also think that with Accelerate, using the `Accelerator` to prepare a dataloader for such a task might also be
+a simple way to manage this. (To learn more, check out the relevant section in the [Quick Tour](../quicktour#distributed-evaluation))
+
+Can it manage it? Yes. Does it add unneeded extra code however: also yes.
+
+
+With Accelerate, we can simplify this process by using the [`Accelerator.split_between_processes`] context manager (which also exists in `PartialState` and `AcceleratorState`).
+This function will automatically split whatever data you pass to it (be it a prompt, a set of tensors, a dictionary of the prior data, etc.) across all the processes (with a potential
+to be padded) for you to use right away.
+
+Let's rewrite the above example using this context manager:
+
+```python
+import torch
+from accelerate import PartialState # Can also be Accelerator or AcceleratorState
+from diffusers import DiffusionPipeline
+
+pipe = DiffusionPipeline.from_pretrained("runwayml/stable-diffusion-v1-5", torch_dtype=torch.float16)
+distributed_state = PartialState()
+pipe.to(distributed_state.device)
+
+# Assume two processes
+with distributed_state.split_between_processes(["a dog", "a cat"]) as prompt:
+ result = pipe(prompt).images[0]
+ result.save(f"result_{distributed_state.process_index}.png")
+```
+
+And then to launch the code, we can use the Accelerate:
+
+If you have generated a config file to be used using `accelerate config`:
+
+```bash
+accelerate launch distributed_inference.py
+```
+
+If you have a specific config file you want to use:
+
+```bash
+accelerate launch --config_file my_config.json distributed_inference.py
+```
+
+Or if don't want to make any config files and launch on two GPUs:
+
+> Note: You will get some warnings about values being guessed based on your system. To remove these you can do `accelerate config default` or go through `accelerate config` to create a config file.
+
+```bash
+accelerate launch --num_processes 2 distributed_inference.py
+```
+
+We've now reduced the boilerplate code needed to split this data to a few lines of code quite easily.
+
+But what if we have an odd distribution of prompts to GPUs? For example, what if we have 3 prompts, but only 2 GPUs?
+
+Under the context manager, the first GPU would receive the first two prompts and the second GPU the third, ensuring that
+all prompts are split and no overhead is needed.
+
+*However*, what if we then wanted to do something with the results of *all the GPUs*? (Say gather them all and perform some kind of post processing)
+You can pass in `apply_padding=True` to ensure that the lists of prompts are padded to the same length, with extra data being taken
+from the last sample. This way all GPUs will have the same number of prompts, and you can then gather the results.
+
+
+
+This is only needed when trying to perform an action such as gathering the results, where the data on each device
+needs to be the same length. Basic inference does not require this.
+
+
+
+For instance:
+
+```python
+import torch
+from accelerate import PartialState # Can also be Accelerator or AcceleratorState
+from diffusers import DiffusionPipeline
+
+pipe = DiffusionPipeline.from_pretrained("runwayml/stable-diffusion-v1-5", torch_dtype=torch.float16)
+distributed_state = PartialState()
+pipe.to(distributed_state.device)
+
+# Assume two processes
+with distributed_state.split_between_processes(["a dog", "a cat", "a chicken"], apply_padding=True) as prompt:
+ result = pipe(prompt).images
+```
+
+On the first GPU, the prompts will be `["a dog", "a cat"]`, and on the second GPU it will be `["a chicken", "a chicken"]`.
+Make sure to drop the final sample, as it will be a duplicate of the previous one.
+
+You can find more complex examples [here](https://github.com/huggingface/accelerate/tree/main/examples/inference/distributed) such as how to use it with LLMs.
+
+## Memory-efficient pipeline parallelism (experimental)
+
+This next part will discuss using *pipeline parallelism*. This is an **experimental** API that utilizes [torch.distributed.pipelining](https://pytorch.org/docs/stable/distributed.pipelining.html#) as a native solution.
+
+The general idea with pipeline parallelism is: say you have 4 GPUs and a model big enough it can be *split* on four GPUs using `device_map="auto"`. With this method you can send in 4 inputs at a time (for example here, any amount works) and each model chunk will work on an input, then receive the next input once the prior chunk finished, making it *much* more efficient **and faster** than the method described earlier. Here's a visual taken from the PyTorch repository:
+
+
+
+To illustrate how you can use this with Accelerate, we have created an [example zoo](https://github.com/huggingface/accelerate/tree/main/examples/inference) showcasing a number of different models and situations. In this tutorial, we'll show this method for GPT2 across two GPUs.
+
+Before you proceed, please make sure you have the latest PyTorch version installed by running the following:
+
+```bash
+pip install torch
+```
+
+Start by creating the model on the CPU:
+
+```{python}
+from transformers import GPT2ForSequenceClassification, GPT2Config
+
+config = GPT2Config()
+model = GPT2ForSequenceClassification(config)
+model.eval()
+```
+
+Next you'll need to create some example inputs to use. These help `torch.distributed.pipelining` trace the model.
+
+
+ However you make this example will determine the relative batch size that will be used/passed
+ through the model at a given time, so make sure to remember how many items there are!
+
+
+```{python}
+input = torch.randint(
+ low=0,
+ high=config.vocab_size,
+ size=(2, 1024), # bs x seq_len
+ device="cpu",
+ dtype=torch.int64,
+ requires_grad=False,
+)
+```
+Next we need to actually perform the tracing and get the model ready. To do so, use the [`inference.prepare_pippy`] function and it will fully wrap the model for pipeline parallelism automatically:
+
+```{python}
+from accelerate.inference import prepare_pippy
+example_inputs = {"input_ids": input}
+model = prepare_pippy(model, example_args=(input,))
+```
+
+
+
+ There are a variety of parameters you can pass through to `prepare_pippy`:
+
+ * `split_points` lets you determine what layers to split the model at. By default we use wherever `device_map="auto" declares, such as `fc` or `conv1`.
+
+ * `num_chunks` determines how the batch will be split and sent to the model itself (so `num_chunks=1` with four split points/four GPUs will have a naive MP where a single input gets passed between the four layer split points)
+
+
+
+From here, all that's left is to actually perform the distributed inference!
+
+
+
+When passing inputs, we highly recommend to pass them in as a tuple of arguments. Using `kwargs` is supported, however, this approach is experimental.
+
+
+```{python}
+args = some_more_arguments
+with torch.no_grad():
+ output = model(*args)
+```
+
+When finished all the data will be on the last process only:
+
+```{python}
+from accelerate import PartialState
+if PartialState().is_last_process:
+ print(output)
+```
+
+
+
+ If you pass in `gather_output=True` to [`inference.prepare_pippy`], the output will be sent
+ across to all the GPUs afterwards without needing the `is_last_process` check. This is
+ `False` by default as it incurs a communication call.
+
+
+
+And that's it! To explore more, please check out the inference examples in the [Accelerate repo](https://github.com/huggingface/accelerate/tree/main/examples/inference/pippy) and our [documentation](../package_reference/inference) as we work to improving this integration.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/explore.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/explore.md
new file mode 100644
index 0000000000000000000000000000000000000000..a2b8cc0d1e1ea733190043d481793bfa805264a5
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/explore.md
@@ -0,0 +1,51 @@
+
+
+# Start Here!
+
+Please use the interactive tool below to help you get started with learning about a particular
+feature of Accelerate and how to utilize it! It will provide you with a code diff, an explanation
+towards what is going on, as well as provide you with some useful links to explore more within
+the documentation!
+
+Most code examples start from the following python code before integrating Accelerate in some way:
+
+```python
+for batch in dataloader:
+ optimizer.zero_grad()
+ inputs, targets = batch
+ inputs = inputs.to(device)
+ targets = targets.to(device)
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets)
+ loss.backward()
+ optimizer.step()
+ scheduler.step()
+```
+
+
+
+
+
+
+
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/fsdp.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/fsdp.md
new file mode 100644
index 0000000000000000000000000000000000000000..a2f9c717a3f359e03fb150cdb1bfeb2183b7eb86
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/fsdp.md
@@ -0,0 +1,200 @@
+
+
+# Fully Sharded Data Parallel
+
+To accelerate training huge models on larger batch sizes, we can use a fully sharded data parallel model.
+This type of data parallel paradigm enables fitting more data and larger models by sharding the optimizer states, gradients and parameters.
+To read more about it and the benefits, check out the [Fully Sharded Data Parallel blog](https://pytorch.org/blog/introducing-pytorch-fully-sharded-data-parallel-api/).
+We have integrated the latest PyTorch's Fully Sharded Data Parallel (FSDP) training feature.
+All you need to do is enable it through the config.
+
+## How it works out of the box
+
+On your machine(s) just run:
+
+```bash
+accelerate config
+```
+
+and answer the questions asked. This will generate a config file that will be used automatically to properly set the
+default options when doing
+
+```bash
+accelerate launch my_script.py --args_to_my_script
+```
+
+For instance, here is how you would run `examples/nlp_example.py` (from the root of the repo) with FSDP enabled:
+
+```bash
+compute_environment: LOCAL_MACHINE
+debug: false
+distributed_type: FSDP
+downcast_bf16: 'no'
+fsdp_config:
+ fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
+ fsdp_backward_prefetch_policy: BACKWARD_PRE
+ fsdp_forward_prefetch: false
+ fsdp_cpu_ram_efficient_loading: true
+ fsdp_offload_params: false
+ fsdp_sharding_strategy: FULL_SHARD
+ fsdp_state_dict_type: SHARDED_STATE_DICT
+ fsdp_sync_module_states: true
+ fsdp_transformer_layer_cls_to_wrap: BertLayer
+ fsdp_use_orig_params: true
+machine_rank: 0
+main_training_function: main
+mixed_precision: bf16
+num_machines: 1
+num_processes: 2
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+```bash
+accelerate launch examples/nlp_example.py
+```
+
+Currently, `Accelerate` supports the following config through the CLI:
+
+`fsdp_sharding_strategy`: [1] FULL_SHARD (shards optimizer states, gradients and parameters), [2] SHARD_GRAD_OP (shards optimizer states and gradients), [3] NO_SHARD (DDP), [4] HYBRID_SHARD (shards optimizer states, gradients and parameters within each node while each node has full copy), [5] HYBRID_SHARD_ZERO2 (shards optimizer states and gradients within each node while each node has full copy). For more information, please refer the official [PyTorch docs](https://pytorch.org/docs/stable/fsdp.html#torch.distributed.fsdp.ShardingStrategy).
+
+`fsdp_offload_params` : Decides Whether to offload parameters and gradients to CPU
+
+`fsdp_auto_wrap_policy`: [1] TRANSFORMER_BASED_WRAP, [2] SIZE_BASED_WRAP, [3] NO_WRAP
+
+`fsdp_transformer_layer_cls_to_wrap`: Only applicable for Transformers. When using `fsdp_auto_wrap_policy=TRANSFORMER_BASED_WRAP`, a user may provide a comma-separated string of transformer layer class names (case-sensitive) to wrap, e.g., `BertLayer`, `GPTJBlock`, `T5Block`, `BertLayer,BertEmbeddings,BertSelfOutput`. This is important because submodules that share weights (e.g., embedding layers) should not end up in different FSDP wrapped units. Using this policy, wrapping happens for each block containing Multi-Head Attention followed by a couple of MLP layers. Remaining layers including the shared embeddings are conveniently wrapped in same outermost FSDP unit. Therefore, use this for transformer-based models. You can use the `model._no_split_modules` for Transformer models by answering `yes` to `Do you want to use the model's `_no_split_modules` to wrap. It will try to use `model._no_split_modules` when possible.
+
+`fsdp_min_num_params`: minimum number of parameters when using `fsdp_auto_wrap_policy=SIZE_BASED_WRAP`.
+
+`fsdp_backward_prefetch_policy`: [1] BACKWARD_PRE, [2] BACKWARD_POST, [3] NO_PREFETCH
+
+`fsdp_forward_prefetch`: if True, then FSDP explicitly prefetches the next upcoming all-gather while executing in the forward pass. Should only be used for static-graph models since the prefetching follows the first iteration’s execution order. i.e., if the sub-modules' order changes dynamically during the model's execution do not enable this feature.
+
+`fsdp_state_dict_type`: [1] FULL_STATE_DICT, [2] LOCAL_STATE_DICT, [3] SHARDED_STATE_DICT
+
+`fsdp_use_orig_params`: If True, allows non-uniform `requires_grad` during init, which means support for interspersed frozen and trainable parameters. This setting is useful in cases such as parameter-efficient fine-tuning as discussed in [this post](https://dev-discuss.pytorch.org/t/rethinking-pytorch-fully-sharded-data-parallel-fsdp-from-first-principles/1019). This option also allows one to have multiple optimizer param groups. This should be `True` when creating an optimizer before preparing/wrapping the model with FSDP.
+
+`fsdp_cpu_ram_efficient_loading`: Only applicable for Transformers models. If True, only the first process loads the pretrained model checkpoint while all other processes have empty weights. This should be set to False if you experience errors when loading the pretrained Transformers model via `from_pretrained` method. When this setting is True `fsdp_sync_module_states` also must to be True, otherwise all the processes except the main process would have random weights leading to unexpected behaviour during training. For this to work, make sure the distributed process group is initialized before calling Transformers `from_pretrained` method. When using Trainer API, the distributed process group is initialized when you create an instance of `TrainingArguments` class.
+
+`fsdp_sync_module_states`: If True, each individually wrapped FSDP unit will broadcast module parameters from rank 0.
+
+
+For additional and more nuanced control, you can specify other FSDP parameters via `FullyShardedDataParallelPlugin`.
+When creating `FullyShardedDataParallelPlugin` object, pass it the parameters that weren't part of the accelerate config or if you want to override them.
+The FSDP parameters will be picked based on the accelerate config file or launch command arguments and other parameters that you will pass directly through the `FullyShardedDataParallelPlugin` object will set/override that.
+
+Below is an example:
+
+```py
+from accelerate import FullyShardedDataParallelPlugin
+from torch.distributed.fsdp.fully_sharded_data_parallel import FullOptimStateDictConfig, FullStateDictConfig
+
+fsdp_plugin = FullyShardedDataParallelPlugin(
+ state_dict_config=FullStateDictConfig(offload_to_cpu=False, rank0_only=False),
+ optim_state_dict_config=FullOptimStateDictConfig(offload_to_cpu=False, rank0_only=False),
+)
+
+accelerator = Accelerator(fsdp_plugin=fsdp_plugin)
+```
+
+## Saving and loading
+
+The new recommended way of checkpointing when using FSDP models is to use `SHARDED_STATE_DICT` as `StateDictType` when setting up the accelerate config.
+Below is the code snippet to save using `save_state` utility of accelerate.
+
+```py
+accelerator.save_state("ckpt")
+```
+
+Inspect the checkpoint folder to see model and optimizer as shards per process:
+```
+ls ckpt
+# optimizer_0 pytorch_model_0 random_states_0.pkl random_states_1.pkl scheduler.bin
+
+cd ckpt
+
+ls optimizer_0
+# __0_0.distcp __1_0.distcp
+
+ls pytorch_model_0
+# __0_0.distcp __1_0.distcp
+```
+
+To load them back for resuming the training, use the `load_state` utility of accelerate
+
+```py
+accelerator.load_state("ckpt")
+```
+
+When using transformers `save_pretrained`, pass `state_dict=accelerator.get_state_dict(model)` to save the model state dict.
+ Below is an example:
+
+```diff
+ unwrapped_model.save_pretrained(
+ args.output_dir,
+ is_main_process=accelerator.is_main_process,
+ save_function=accelerator.save,
++ state_dict=accelerator.get_state_dict(model),
+)
+```
+
+### State Dict
+
+`accelerator.get_state_dict` will call the underlying `model.state_dict` implementation using `FullStateDictConfig(offload_to_cpu=True, rank0_only=True)` context manager to get the state dict only for rank 0 and it will be offloaded to CPU.
+
+You can then pass `state` into the `save_pretrained` method. There are several modes for `StateDictType` and `FullStateDictConfig` that you can use to control the behavior of `state_dict`. For more information, see the [PyTorch documentation](https://pytorch.org/docs/stable/fsdp.html).
+
+If you choose to use `StateDictType.SHARDED_STATE_DICT`, the weights of the model during `Accelerator.save_state` will be split into `n` files for each sub-split on the model. To merge them back into
+a single dictionary to load back into the model later after training you can use the `merge_weights` utility:
+
+```py
+from accelerate.utils import merge_fsdp_weights
+
+# Our weights are saved usually in a `pytorch_model_fsdp_{model_number}` folder
+merge_fsdp_weights("pytorch_model_fsdp_0", "output_path", safe_serialization=True)
+```
+The final output will then either be saved to `model.safetensors` or `pytorch_model.bin` (if `safe_serialization=False` is passed).
+
+This can also be called using the CLI:
+```bash
+accelerate merge-weights pytorch_model_fsdp_0/ output_path
+```
+
+
+## Mapping between FSDP sharding strategies and DeepSpeed ZeRO Stages
+* `FULL_SHARD` maps to the DeepSpeed `ZeRO Stage-3`. Shards optimizer states, gradients and parameters.
+* `SHARD_GRAD_OP` maps to the DeepSpeed `ZeRO Stage-2`. Shards optimizer states and gradients.
+* `NO_SHARD` maps to `ZeRO Stage-0`. No sharding wherein each GPU has full copy of model, optimizer states and gradients.
+* `HYBRID_SHARD` maps to `ZeRO++ Stage-3` wherein `zero_hpz_partition_size=`. Here, this will shard optimizer states, gradients and parameters within each node while each node has full copy.
+
+## A few caveats to be aware of
+
+- In case of multiple models, pass the optimizers to the prepare call in the same order as corresponding models else `accelerator.save_state()` and `accelerator.load_state()` will result in wrong/unexpected behaviour.
+- This feature is incompatible with `--predict_with_generate` in the `run_translation.py` script of `Transformers` library.
+
+For more control, users can leverage the `FullyShardedDataParallelPlugin`. After creating an instance of this class, users can pass it to the Accelerator class instantiation.
+For more information on these options, please refer to the PyTorch [FullyShardedDataParallel](https://github.com/pytorch/pytorch/blob/0df2e863fbd5993a7b9e652910792bd21a516ff3/torch/distributed/fsdp/fully_sharded_data_parallel.py#L236) code.
+
+
+
+
+ For those interested in the similarities and differences between FSDP and DeepSpeed, please check out the [concept guide here](../concept_guides/fsdp_and_deepspeed)!
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/gaudi.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/gaudi.md
new file mode 100644
index 0000000000000000000000000000000000000000..3b7373c296f84ec3abe304ba7dc2b7c3620664d3
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/gaudi.md
@@ -0,0 +1,38 @@
+
+
+# Intel Gaudi
+
+Users can take advantage of Intel Gaudi AI accelerators for significantly faster and cost-effective model training and inference.
+The Intel Gaudi AI accelerator family currently includes three product generations: [Intel Gaudi 1](https://habana.ai/products/gaudi/), [Intel Gaudi 2](https://habana.ai/products/gaudi2/), and [Intel Gaudi 3](https://habana.ai/products/gaudi3/). Each server is equipped with 8 devices, known as Habana Processing Units (HPUs), providing 128GB of memory on Gaudi 3, 96GB on Gaudi 2, and 32GB on the first-gen Gaudi. For more details on the underlying hardware architecture, check out the [Gaudi Architecture Overview](https://docs.habana.ai/en/latest/Gaudi_Overview/Gaudi_Architecture.html).
+
+## How it works out of the box
+
+It is enabled by default if an Intel Gaudi device is detected.
+To disable it, pass `--cpu` flag to `accelerate launch` command or answer the corresponding question when answering the `accelerate config` questionnaire.
+
+You can directly run the following script to test it out on Intel Gaudi:
+
+```bash
+accelerate launch /examples/cv_example.py --data_dir images
+```
+
+## Limitations
+
+The following features are not part of the Accelerate library and requires [Optimum for Intel Gaudi](https://huggingface.co/docs/optimum/main/en/habana/index):
+
+- `fast_ddp` which implements DDP by applying an all-reduce on gradients instead of the Torch DDP wrapper.
+- `minimize_memory` which is used for fp8 training and enables keeping fp8 weights in memory between the forward and backward passes, leading to a smaller memory footprint at the cost of additional fp8 casts.
+- `context_parallel_size` which is used for Context/Sequence Parallelism (CP/SP) and partitions the network inputs and activations along sequence dimension to reduce memory footprint and increase throughput.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/gradient_accumulation.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/gradient_accumulation.md
new file mode 100644
index 0000000000000000000000000000000000000000..4e0ae3d27a465681f88a3c7c8355d82b2af48423
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/gradient_accumulation.md
@@ -0,0 +1,470 @@
+
+
+# Performing gradient accumulation with Accelerate
+
+Gradient accumulation is a technique where you can train on bigger batch sizes than
+your machine would normally be able to fit into memory. This is done by accumulating gradients over
+several batches, and only stepping the optimizer after a certain number of batches have been performed.
+
+While technically standard gradient accumulation code would work fine in a distributed setup, it is not the most efficient
+method for doing so and you may experience considerable slowdowns!
+
+In this tutorial you will see how to quickly setup gradient accumulation and perform it with the utilities provided in Accelerate,
+which can total to adding just one new line of code!
+
+This example will use a very simplistic PyTorch training loop that performs gradient accumulation every two batches:
+
+```python
+device = "cuda"
+model.to(device)
+
+gradient_accumulation_steps = 2
+
+for index, batch in enumerate(training_dataloader):
+ inputs, targets = batch
+ inputs = inputs.to(device)
+ targets = targets.to(device)
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets)
+ loss = loss / gradient_accumulation_steps
+ loss.backward()
+ if (index + 1) % gradient_accumulation_steps == 0:
+ optimizer.step()
+ scheduler.step()
+ optimizer.zero_grad()
+```
+
+## Converting it to Accelerate
+
+First the code shown earlier will be converted to utilize Accelerate without the special gradient accumulation helper:
+
+```diff
++ from accelerate import Accelerator
++ accelerator = Accelerator()
+
++ model, optimizer, training_dataloader, scheduler = accelerator.prepare(
++ model, optimizer, training_dataloader, scheduler
++ )
+
+ for index, batch in enumerate(training_dataloader):
+ inputs, targets = batch
+- inputs = inputs.to(device)
+- targets = targets.to(device)
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets)
+ loss = loss / gradient_accumulation_steps
++ accelerator.backward(loss)
+ if (index+1) % gradient_accumulation_steps == 0:
+ optimizer.step()
+ scheduler.step()
+ optimizer.zero_grad()
+```
+
+
+
+ In its current state, this code is not going to perform gradient accumulation efficiently due to a process called gradient synchronization. Read more about that in the [Concepts tutorial](../concept_guides/gradient_synchronization)!
+
+
+
+## Letting Accelerate handle gradient accumulation
+
+All that is left now is to let Accelerate handle the gradient accumulation for us. To do so you should pass in a `gradient_accumulation_steps` parameter to [`Accelerator`], dictating the number
+of steps to perform before each call to `step()` and how to automatically adjust the loss during the call to [`~Accelerator.backward`]:
+
+```diff
+ from accelerate import Accelerator
+- accelerator = Accelerator()
++ accelerator = Accelerator(gradient_accumulation_steps=2)
+```
+
+Alternatively, you can pass in a `gradient_accumulation_plugin` parameter to the [`Accelerator`] object's `__init__`, which will allow you to further customize the gradient accumulation behavior.
+Read more about that in the [GradientAccumulationPlugin](../package_reference/accelerator#accelerate.utils.GradientAccumulationPlugin) docs.
+
+From here you can use the [`~Accelerator.accumulate`] context manager from inside your training loop to automatically perform the gradient accumulation for you!
+You just wrap it around the entire training part of our code:
+
+```diff
+- for index, batch in enumerate(training_dataloader):
++ for batch in training_dataloader:
++ with accelerator.accumulate(model):
+ inputs, targets = batch
+ outputs = model(inputs)
+```
+
+You can remove all the special checks for the step number and the loss adjustment:
+
+```diff
+- loss = loss / gradient_accumulation_steps
+ accelerator.backward(loss)
+- if (index+1) % gradient_accumulation_steps == 0:
+ optimizer.step()
+ scheduler.step()
+ optimizer.zero_grad()
+```
+
+As you can see the [`Accelerator`] is able to keep track of the batch number you are on and it will automatically know whether to step through the prepared optimizer and how to adjust the loss.
+
+
+
+Typically with gradient accumulation, you would need to adjust the number of steps to reflect the change in total batches you are
+training on. Accelerate automagically does this for you by default. Behind the scenes we instantiate a [`GradientAccumulationPlugin`] configured to do this.
+
+
+
+
+
+The [`state.GradientState`] is sync'd with the active dataloader being iterated upon. As such it assumes naively that when we have reached the end of the dataloader everything will sync and a step will be performed. To disable this, set `sync_with_dataloader` to be `False` in the [`GradientAccumulationPlugin`]:
+
+```{python}
+from accelerate import Accelerator
+from accelerate.utils import GradientAccumulationPlugin
+
+plugin = GradientAccumulationPlugin(sync_with_dataloader=False)
+accelerator = Accelerator(..., gradient_accumulation_plugin=plugin)
+```
+
+
+
+## The finished code
+
+Below is the finished implementation for performing gradient accumulation with Accelerate
+
+```python
+from accelerate import Accelerator
+accelerator = Accelerator(gradient_accumulation_steps=2)
+model, optimizer, training_dataloader, scheduler = accelerator.prepare(
+ model, optimizer, training_dataloader, scheduler
+)
+for batch in training_dataloader:
+ with accelerator.accumulate(model):
+ inputs, targets = batch
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets)
+ accelerator.backward(loss)
+ optimizer.step()
+ scheduler.step()
+ optimizer.zero_grad()
+```
+
+
+
+It's important that **only one forward/backward** should be done inside the context manager `with accelerator.accumulate(model)`.
+
+
+
+
+To learn more about what magic this wraps around, read the [Gradient Synchronization concept guide](../concept_guides/gradient_synchronization)
+
+
+## Self-contained example
+
+Here is a self-contained example that you can run to see gradient accumulation in action with Accelerate:
+
+```python
+import torch
+import copy
+from accelerate import Accelerator
+from accelerate.utils import set_seed
+from torch.utils.data import TensorDataset, DataLoader
+
+# seed
+set_seed(0)
+
+# define toy inputs and labels
+x = torch.tensor([1., 2., 3., 4., 5., 6., 7., 8.])
+y = torch.tensor([2., 4., 6., 8., 10., 12., 14., 16.])
+gradient_accumulation_steps = 4
+per_device_batch_size = len(x) // gradient_accumulation_steps
+
+# define dataset and dataloader
+dataset = TensorDataset(x, y)
+dataloader = DataLoader(dataset, batch_size=per_device_batch_size)
+
+# define model, optimizer and loss function
+class SimpleLinearModel(torch.nn.Module):
+ def __init__(self):
+ super(SimpleLinearModel, self).__init__()
+ self.weight = torch.nn.Parameter(torch.zeros((1, 1)))
+
+ def forward(self, inputs):
+ return inputs @ self.weight
+
+model = SimpleLinearModel()
+model_clone = copy.deepcopy(model)
+criterion = torch.nn.MSELoss()
+model_optimizer = torch.optim.SGD(model.parameters(), lr=0.02)
+accelerator = Accelerator(gradient_accumulation_steps=gradient_accumulation_steps)
+model, model_optimizer, dataloader = accelerator.prepare(model, model_optimizer, dataloader)
+model_clone_optimizer = torch.optim.SGD(model_clone.parameters(), lr=0.02)
+print(f"initial model weight is {model.weight.mean().item():.5f}")
+print(f"initial model weight is {model_clone.weight.mean().item():.5f}")
+for i, (inputs, labels) in enumerate(dataloader):
+ with accelerator.accumulate(model):
+ inputs = inputs.view(-1, 1)
+ print(i, inputs.flatten())
+ labels = labels.view(-1, 1)
+ outputs = model(inputs)
+ loss = criterion(outputs, labels)
+ accelerator.backward(loss)
+ model_optimizer.step()
+ model_optimizer.zero_grad()
+loss = criterion(x.view(-1, 1) @ model_clone.weight, y.view(-1, 1))
+model_clone_optimizer.zero_grad()
+loss.backward()
+model_clone_optimizer.step()
+print(f"w/ accumulation, the final model weight is {model.weight.mean().item():.5f}")
+print(f"w/o accumulation, the final model weight is {model_clone.weight.mean().item():.5f}")
+```
+```
+initial model weight is 0.00000
+initial model weight is 0.00000
+0 tensor([1., 2.])
+1 tensor([3., 4.])
+2 tensor([5., 6.])
+3 tensor([7., 8.])
+w/ accumulation, the final model weight is 2.04000
+w/o accumulation, the final model weight is 2.04000
+```
+
+## Gradient accumulation on training samples of variable size
+
+As was pointed out in this [blog-post](https://huggingface.co/blog/gradient_accumulation), which points out a common error that occurs when performing gradient accumulation on training samples of variable size:
+
+> [...] for gradient accumulation across token-level tasks like causal LM training, the correct loss should be computed by the **total loss across all batches in a gradient accumulation step** divided by the **total number of all non padding tokens in those batches**. This is not the same as the average of the per-batch loss values.
+
+In other words, some adjustments must be made on losses that operate on a token-level basis.
+
+### Skeleton code
+
+```python
+from accelerate import Accelerator
+import math
+import contextlib
+
+gradient_accumulation_steps = 2
+accelerator = Accelerator(gradient_accumulation_steps=gradient_accumulation_steps)
+model, optimizer, training_dataloader, scheduler = accelerator.prepare(
+ model, optimizer, training_dataloader, scheduler
+)
+
+training_iterator = iter(training_dataloader)
+num_samples_in_epoch = len(training_dataloader)
+remainder = num_samples_in_epoch % gradient_accumulation_steps
+remainder = remainder if remainder != 0 else gradient_accumulation_steps
+total_updates = math.ceil(num_samples_in_epoch / gradient_accumulation_steps)
+
+
+total_batched_samples = 0
+for update_step in range(total_updates):
+ # In order to correctly the total number of non-padded tokens on which we'll compute the cross-entropy loss
+ # we need to pre-load the full local batch - i.e the next per_device_batch_size * accumulation_steps samples
+ batch_samples = []
+ num_batches_in_step = gradient_accumulation_steps if update_step != (total_updates - 1) else remainder
+ for _ in range(num_batches_in_step):
+ batch_samples += [next(training_iterator)]
+
+ # get local num items in batch
+ num_items_in_batch = sum([(batch["labels"].ne(-100)).sum() for batch in batch_samples])
+ # to compute it correctly in a multi-device DDP training, we need to gather the total number of items in the full batch.
+ num_items_in_batch = accelerator.gather(num_items_in_batch).sum().item()
+
+ for i, batch in enumerate(batch_samples):
+ # if we perform gradient accumulation in a multi-devices set-up, we want to avoid unnecessary communications when accumulating
+ # cf: https://muellerzr.github.io/blog/gradient_accumulation.html
+ if (i < len(batch_samples) - 1 and accelerator.num_processes > 1):
+ ctx = model.no_sync
+ else:
+ ctx = contextlib.nullcontext
+
+ total_batched_samples += 1
+
+ with ctx():
+ inputs, targets = batch
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets) # the loss function should sum over samples rather than averaging
+
+ # We multiply by num_processes because the DDP calculates the average gradient across all devices whereas dividing by num_items_in_batch already takes into account all devices
+ # Same reason for gradient_accumulation_steps, but this times it's Accelerate that calculate the average gradient across the accumulated steps
+ loss = (loss * gradient_accumulation_steps * accelerator.num_processes) / num_items_in_batch
+
+ accelerator.backward(loss)
+
+ # Sync gradients and perform optimization steps once every gradient_accumulation_steps
+ optimizer.step()
+ scheduler.step()
+ optimizer.zero_grad()
+```
+
+### Self-contained causal LM example
+
+```py
+import torch
+import copy
+from accelerate import Accelerator
+from accelerate.utils import set_seed
+from accelerate.logging import get_logger
+from torch.utils.data import Dataset, DataLoader
+import math
+import contexlib
+
+# seed
+set_seed(0)
+logger = get_logger(__name__)
+
+class MyDataset(Dataset):
+ def __init__(self, num_samples):
+ super().__init__()
+ self.len = num_samples
+
+ def __getitem__(self, index):
+ input_ids = torch.arange(1, index+2, dtype=torch.float32)
+ labels = torch.remainder(input_ids, 2)
+ return {"input_ids": input_ids, "labels": labels}
+
+ def __len__(self):
+ return self.len
+
+def collate_fn(features):
+ input_ids = torch.nn.utils.rnn.pad_sequence([f["input_ids"] for f in features], batch_first=True, padding_value=-100)
+ labels = torch.nn.utils.rnn.pad_sequence([f["labels"] for f in features], batch_first=True, padding_value=-100)
+ return {"input_ids": input_ids[..., None], "labels": labels[..., None]}
+
+# define toy inputs and labels
+gradient_accumulation_steps = 2
+per_device_batch_size = 4
+
+# define accelerator
+accelerator = Accelerator(gradient_accumulation_steps=gradient_accumulation_steps)
+
+# define dataset and dataloader
+# for this toy example, we'll compute gradient descent over one single global batch
+dataset = MyDataset(per_device_batch_size*gradient_accumulation_steps*accelerator.num_processes)
+dataloader = DataLoader(dataset, batch_size=per_device_batch_size, collate_fn=collate_fn)
+
+# define model, model_optimizer and loss function
+model = torch.nn.Linear(1, 2, bias=False)
+model_clone = copy.deepcopy(model)
+criterion = torch.nn.CrossEntropyLoss(reduction="sum") # must sum over samples rather than averaging
+model_optimizer = torch.optim.SGD(model.parameters(), lr=0.08)
+
+
+logger.warning(f"initial model weight is {model.weight.detach().cpu().squeeze()}")
+logger.warning(f"initial model clone weight is {model_clone.weight.detach().cpu().squeeze()}")
+
+# prepare artifacts - accelerator handles device placement and dataloader splitting
+model, model_optimizer = accelerator.prepare(model, model_optimizer)
+dataloader = accelerator.prepare_data_loader(dataloader, device_placement=True)
+training_iterator = iter(dataloader)
+
+num_samples_in_epoch = len(dataloader)
+remainder = num_samples_in_epoch % gradient_accumulation_steps
+remainder = remainder if remainder != 0 else gradient_accumulation_steps
+total_gradient_updates = math.ceil(num_samples_in_epoch / gradient_accumulation_steps)
+
+total_batched_samples = 0
+for update_step in range(total_gradient_updates):
+ # In order to correctly the total number of non-padded tokens on which we'll compute the cross-entropy loss
+ # we need to pre-load the full local batch - i.e the next per_device_batch_size * accumulation_steps samples
+ batch_samples = []
+ num_batches_in_step = gradient_accumulation_steps if update_step != (total_gradient_updates - 1) else remainder
+ for _ in range(num_batches_in_step):
+ batch_samples += [next(training_iterator)]
+
+ # get local num items in batch
+ local_num_items_in_batch = sum([(batch["labels"].ne(-100)).sum() for batch in batch_samples])
+ logger.warning(f"Step {update_step} - Device {accelerator.process_index} - num items in the local batch {local_num_items_in_batch}", main_process_only=False)
+
+ # to compute it correctly in a multi-device DDP training, we need to gather the total number of items in the full batch.
+ num_items_in_batch = accelerator.gather(local_num_items_in_batch).sum().item()
+ logger.warning(f"Total num items {num_items_in_batch}")
+
+ for i, batch in enumerate(batch_samples):
+ inputs, labels = batch["input_ids"], batch["labels"]
+ total_batched_samples += 1
+ # if we perform gradient accumulation in a multi-devices set-up, we want to avoid unnecessary communications when accumulating
+ # cf: https://muellerzr.github.io/blog/gradient_accumulation.html
+ if (i < len(batch_samples) - 1 and accelerator.num_processes > 1):
+ ctx = model.no_sync
+ else:
+ ctx = contextlib.nullcontext
+ with ctx():
+
+ outputs = model(inputs)
+ loss = criterion(outputs.view(-1, 2), labels.view(-1).to(torch.int64))
+
+ # We multiply by num_processes because the DDP calculates the average gradient across all devices whereas dividing by num_items_in_batch already takes into account all devices
+ # Same reason for gradient_accumulation_steps, but this times it's Accelerate that calculate the average gradient across the accumulated steps
+ loss = (loss * gradient_accumulation_steps * accelerator.num_processes) / num_items_in_batch
+ accelerator.backward(loss)
+ model_optimizer.step()
+ model_optimizer.zero_grad()
+
+
+logger.warning(f"Device {accelerator.process_index} - w/ accumulation, the final model weight is {accelerator.unwrap_model(model).weight.detach().cpu().squeeze()}", main_process_only=False)
+
+# We know do the same operation but on a single device and without gradient accumulation
+
+if accelerator.is_main_process:
+ # prepare one single entire batch
+ dataloader = DataLoader(dataset, batch_size=len(dataset), collate_fn=collate_fn)
+ full_batch_without_accum = next(iter(dataloader))
+ total_inputs, total_labels = full_batch_without_accum["input_ids"], full_batch_without_accum["labels"]
+ model_clone_optimizer = torch.optim.SGD(model_clone.parameters(), lr=0.08)
+
+ # train the cloned model
+ loss = torch.nn.CrossEntropyLoss(reduction="mean")(model_clone(total_inputs).view(-1, 2), total_labels.view(-1).to(torch.int64))
+ model_clone_optimizer.zero_grad()
+ loss.backward()
+ model_clone_optimizer.step()
+
+ # We should have the same final weights.
+ logger.warning(f"w/o accumulation, the final model weight is {model_clone.weight.detach().cpu().squeeze()}")
+
+```
+
+Results on a single device - gradient accumulation steps set to 1 and batch_size set to 8:
+```
+initial model weight is tensor([-0.0075, 0.5364])
+initial model clone weight is tensor([-0.0075, 0.5364])
+Step 0 - Device 0 - num items in the local batch 36
+Total num items 36
+Device 0 - w/ accumulation, the final model weight is tensor([0.0953, 0.4337])
+w/o accumulation, the final model weight is tensor([0.0953, 0.4337])
+```
+
+Results on a two devices set-up - gradient accumulation steps set to 2 and batch_size set to 4.
+```
+initial model weight is tensor([-0.0075, 0.5364])
+initial model clone weight is tensor([-0.0075, 0.5364])
+Step 0 - Device 0 - num items in the local batch 52
+Step 0 - Device 1 - num items in the local batch 84
+Total num items 136
+Device 1 - w/ accumulation, the final model weight is tensor([0.2117, 0.3172])
+Device 0 - w/ accumulation, the final model weight is tensor([0.2117, 0.3172])
+w/o accumulation, the final model weight is tensor([0.2117, 0.3172])
+```
+
+### To go further:
+
+Please find a complete example script on a real world training run in the examples folder at the path [`accelerate/examples/by_feature/gradient_accumulation_for_autoregressive_models.py`](https://github.com/huggingface/accelerate/blob/main/examples/by_feature/gradient_accumulation_for_autoregressive_models.py).
+
+Running it on several training configurations with constant global batch size equal to 32 gives the following graph:
+
+
+
+
+
+Note that the training losses are exactly the same up to training step 20. The small deviation after this training step occurs at the very end of the first epoch, because, by [default](https://huggingface.co/docs/accelerate/en/package_reference/torch_wrappers#accelerate.data_loader.prepare_data_loader.even_batches), the dataloader duplicates the samples at the beginning of the dataset when the total batch size doesn't exactly divide the dataset.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/intel_cpu.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/intel_cpu.md
new file mode 100644
index 0000000000000000000000000000000000000000..309fa8b5c5c7bdf6ceb740731c3fdfc075166c49
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/intel_cpu.md
@@ -0,0 +1,159 @@
+
+
+# Training on Intel CPU
+
+## How It Works For Training optimization in CPU
+
+Accelerate has full support for Intel CPU, all you need to do is enabling it through the config.
+
+**Scenario 1**: Acceleration of No distributed CPU training
+
+Run accelerate config on your machine:
+
+```bash
+$ accelerate config
+-----------------------------------------------------------------------------------------------------------------------------------------------------------
+In which compute environment are you running?
+This machine
+-----------------------------------------------------------------------------------------------------------------------------------------------------------
+Which type of machine are you using?
+No distributed training
+Do you want to run your training on CPU only (even if a GPU / Apple Silicon device is available)? [yes/NO]:yes
+Do you wish to optimize your script with torch dynamo?[yes/NO]:NO
+Do you want to use DeepSpeed? [yes/NO]: NO
+-----------------------------------------------------------------------------------------------------------------------------------------------------------
+Do you wish to use FP16 or BF16 (mixed precision)?
+bf16
+```
+This will generate a config file that will be used automatically to properly set the
+default options when doing
+
+```bash
+accelerate launch my_script.py --args_to_my_script
+```
+
+For instance, here is how you would run the NLP example `examples/nlp_example.py` (from the root of the repo) with `default_config.yaml` which is generated by `accelerate config`
+
+```bash
+compute_environment: LOCAL_MACHINE
+distributed_type: 'NO'
+downcast_bf16: 'no'
+machine_rank: 0
+main_training_function: main
+mixed_precision: bf16
+num_machines: 1
+num_processes: 1
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: true
+```
+```bash
+accelerate launch examples/nlp_example.py
+```
+
+> [!CAUTION]
+> `accelerator.prepare` can currently only handle simultaneously preparing multiple models (and no optimizer) OR a single model-optimizer pair for training. Other attempts (e.g., two model-optimizer pairs) will raise a verbose error. To work around this limitation, consider separately using `accelerator.prepare` for each model-optimizer pair.
+
+**Scenario 2**: Acceleration of distributed CPU training
+we use Intel oneCCL for communication, combined with Intel® MPI library to deliver flexible, efficient, scalable cluster messaging on Intel® architecture. you could refer the [here](https://huggingface.co/docs/transformers/perf_train_cpu_many) for the installation guide
+
+Run accelerate config on your machine(node0):
+
+```bash
+$ accelerate config
+-----------------------------------------------------------------------------------------------------------------------------------------------------------
+In which compute environment are you running?
+This machine
+-----------------------------------------------------------------------------------------------------------------------------------------------------------
+Which type of machine are you using?
+multi-CPU
+How many different machines will you use (use more than 1 for multi-node training)? [1]: 4
+-----------------------------------------------------------------------------------------------------------------------------------------------------------
+What is the rank of this machine?
+0
+What is the IP address of the machine that will host the main process? 36.112.23.24
+What is the port you will use to communicate with the main process? 29500
+Are all the machines on the same local network? Answer `no` if nodes are on the cloud and/or on different network hosts [YES/no]: yes
+Do you want accelerate to launch mpirun? [yes/NO]: yes
+Please enter the path to the hostfile to use with mpirun [~/hostfile]: ~/hostfile
+Enter the number of oneCCL worker threads [1]: 1
+Do you wish to optimize your script with torch dynamo?[yes/NO]:NO
+How many processes should be used for distributed training? [1]:16
+-----------------------------------------------------------------------------------------------------------------------------------------------------------
+Do you wish to use FP16 or BF16 (mixed precision)?
+bf16
+```
+For instance, here is how you would run the NLP example `examples/nlp_example.py` (from the root of the repo) with IPEX enabled for distributed CPU training.
+
+`default_config.yaml` which is generated by `accelerate config`
+```bash
+compute_environment: LOCAL_MACHINE
+distributed_type: MULTI_CPU
+downcast_bf16: 'no'
+machine_rank: 0
+main_process_ip: 36.112.23.24
+main_process_port: 29500
+main_training_function: main
+mixed_precision: bf16
+mpirun_config:
+ mpirun_ccl: '1'
+ mpirun_hostfile: /home/user/hostfile
+num_machines: 4
+num_processes: 16
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: true
+```
+
+Set following env and using intel MPI to launch the training
+
+In `node0`, you need to create a configuration file which contains the IP addresses of each node (for example hostfile) and pass that configuration file path as an argument.
+
+If you selected to let Accelerate launch `mpirun`, ensure that the location of your hostfile matches the path in the config.
+
+```bash
+$ cat hostfile
+xxx.xxx.xxx.xxx #node0 ip
+xxx.xxx.xxx.xxx #node1 ip
+xxx.xxx.xxx.xxx #node2 ip
+xxx.xxx.xxx.xxx #node3 ip
+```
+
+Before executing `accelerate launch` command, you need source the oneCCL bindings `setvars.sh` to get your Intel MPI environment properly. Note that both the python script and environment need to be available on all of the machines being used for multi-CPU training.
+
+```bash
+oneccl_bindings_for_pytorch_path=$(python -c "from oneccl_bindings_for_pytorch import cwd; print(cwd)")
+source $oneccl_bindings_for_pytorch_path/env/setvars.sh
+
+accelerate launch examples/nlp_example.py
+```
+
+You can also directly launch distributed training with `mpirun` command, you need to run the following command in node0 and **16DDP** will be enabled in node0,node1,node2,node3 with BF16 mixed precision. When using this method, the python script, python environment, and accelerate config file need to be available on all of the machines used for multi-CPU training.
+
+```bash
+oneccl_bindings_for_pytorch_path=$(python -c "from oneccl_bindings_for_pytorch import cwd; print(cwd)")
+source $oneccl_bindings_for_pytorch_path/env/setvars.sh
+export CCL_WORKER_COUNT=1
+export MASTER_ADDR=xxx.xxx.xxx.xxx #node0 ip
+export CCL_ATL_TRANSPORT=ofi
+mpirun -f hostfile -n 16 -ppn 4 accelerate launch examples/nlp_example.py
+```
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/local_sgd.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/local_sgd.md
new file mode 100644
index 0000000000000000000000000000000000000000..ea71ad29d8122be0f30d239e6032567005b531e0
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/local_sgd.md
@@ -0,0 +1,108 @@
+
+
+# Using Local SGD with Accelerate
+
+Local SGD is a technique for distributed training where gradients are not synchronized every step. Thus, each process updates its own version of the model weights and after a given number of steps these weights are synchronized by averaging across all processes. This improves communication efficiency and can lead to substantial training speed up especially when a computer lacks a faster interconnect such as NVLink.
+Unlike gradient accumulation (where improving communication efficiency requires increasing the effective batch size), Local SGD does not require changing a batch size or a learning rate / schedule. However, if necessary, Local SGD can be combined with gradient accumulation as well.
+
+In this tutorial you will see how to quickly setup Local SGD Accelerate. Compared to a standard Accelerate setup, this requires only two extra lines of code.
+
+This example will use a very simplistic PyTorch training loop that performs gradient accumulation every two batches:
+
+```python
+device = "cuda"
+model.to(device)
+
+gradient_accumulation_steps = 2
+
+for index, batch in enumerate(training_dataloader):
+ inputs, targets = batch
+ inputs = inputs.to(device)
+ targets = targets.to(device)
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets)
+ loss = loss / gradient_accumulation_steps
+ loss.backward()
+ if (index + 1) % gradient_accumulation_steps == 0:
+ optimizer.step()
+ scheduler.step()
+ optimizer.zero_grad()
+```
+
+## Converting it to Accelerate
+
+First the code shown earlier will be converted to use Accelerate with neither a LocalSGD or a gradient accumulation helper:
+
+```diff
++ from accelerate import Accelerator
++ accelerator = Accelerator()
+
++ model, optimizer, training_dataloader, scheduler = accelerator.prepare(
++ model, optimizer, training_dataloader, scheduler
++ )
+
+ for index, batch in enumerate(training_dataloader):
+ inputs, targets = batch
+- inputs = inputs.to(device)
+- targets = targets.to(device)
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets)
+ loss = loss / gradient_accumulation_steps
++ accelerator.backward(loss)
+ if (index+1) % gradient_accumulation_steps == 0:
+ optimizer.step()
+ scheduler.step()
+```
+
+## Letting Accelerate handle model synchronization
+
+All that is left now is to let Accelerate handle model parameter synchronization **and** the gradient accumulation for us. For simplicity let us assume we need to synchronize every 8 steps. This is
+achieved by adding one `with LocalSGD` statement and one call `local_sgd.step()` after every optimizer step:
+
+```diff
++local_sgd_steps=8
+
++with LocalSGD(accelerator=accelerator, model=model, local_sgd_steps=8, enabled=True) as local_sgd:
+ for batch in training_dataloader:
+ with accelerator.accumulate(model):
+ inputs, targets = batch
+ outputs = model(inputs)
+ loss = loss_function(outputs, targets)
+ accelerator.backward(loss)
+ optimizer.step()
+ scheduler.step()
+ optimizer.zero_grad()
++ local_sgd.step()
+```
+
+Under the hood, the Local SGD code **disables** automatic gradient synchronization (but accumulation still works as expected!). Instead it averages model parameters every `local_sgd_steps` steps (as well as at the end of the training loop).
+
+## Limitations
+
+The current implementation works only with basic multi-GPU (or multi-CPU) training without, e.g., [DeepSpeed.](https://github.com/deepspeedai/DeepSpeed).
+
+## References
+
+ Although we are not aware of the true origins of this simple approach, the idea of local SGD is quite old and goes
+ back to at least:
+
+ Zhang, J., De Sa, C., Mitliagkas, I., & Ré, C. (2016). [Parallel SGD: When does averaging help?. arXiv preprint
+ arXiv:1606.07365.](https://huggingface.co/papers/1606.07365)
+
+ We credit the term Local SGD to the following paper (but there might be earlier references we are not aware of).
+
+ Stich, Sebastian Urban. ["Local SGD Converges Fast and Communicates Little." ICLR 2019-International Conference on
+ Learning Representations. No. CONF. 2019.](https://huggingface.co/papers/1805.09767)
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/low_precision_training.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/low_precision_training.md
new file mode 100644
index 0000000000000000000000000000000000000000..2d81dcb88850f7e2a6130f1360a2fb28ee0f48ae
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/low_precision_training.md
@@ -0,0 +1,164 @@
+
+
+# Low Precision Training Methods
+
+Accelerate provides integrations to train on lower precision methods using specified supported hardware through the `TransformersEngine`, `MS-AMP`, and `torchao` packages. This documentation will help guide you through what hardware is supported, how to configure your [`Accelerator`] to leverage the low precision methods, and what you can expect when training.
+
+## What training on FP8 means
+
+To explore more of the nitty-gritty in training in FP8 with PyTorch and Accelerate, check out the [concept_guide](../concept_guides/low_precision_training) on why this can be difficult. But essentially rather than training in BF16, some (or all) aspects of training a model can be performed using 8 bits instead of 16. The challenge is doing so without degrading final performance.
+
+This is only enabled on specific NVIDIA hardware, namely:
+
+* Anything after the 3000 series consumer graphics cards (such as the 4090)
+* Hopper-based GPU architectures (such as the `H100` and `H200`)
+
+What this will result in is some reduction in the memory used (as we've cut the needed memory in half for some parts of training) and an increase in throughput *should* be seen as well for larger models that can replace certain layers with FP8-enabled ones.
+
+## Configuring the Accelerator
+
+Currently three different backends for FP8 are supported (`TransformersEngine`, `torchao`, and `MS-AMP`), each with different capabilities and configurations.
+
+To use either, the same core API is used. Just pass `mixed_precision="fp8"` to either the [`Accelerator`], during `accelerate config` when prompted about mixed precision, or as part of your `config.yaml` file in the `mixed_precision` key:
+
+```{python}
+from accelerate import Accelerator
+accelerator = Accelerator(mixed_precision="fp8")
+```
+
+By default, if `MS-AMP` is available in your environment, Accelerate will automatically utilize it as a backend. To specify it yourself (and customize other parts of the FP8 mixed precision setup), you can utilize one of the `RecipeKwargs` dataclasses such as [`utils.AORecipeKwargs`], [`utils.TERecipeKwargs`], or [`utils.MSAMPRecipeKwargs`]; you can also clarify it in your config `yaml`/during `accelerate launch`:
+
+```{python}
+from accelerate import Accelerator
+from accelerate.utils import MSAMPRecipeKwargs
+kwargs = [MSAMPRecipeKwargs()]
+# Or to specify the backend as `TransformersEngine` even if MS-AMP is installed
+# kwargs = [TERecipeKwargs()]
+# Or to use torchao
+# kwargs = [AORecipeKwargs()]
+accelerator = Accelerator(mixed_precision="fp8", kwarg_handlers=kwargs)
+```
+
+```{yaml}
+mixed_precision: fp8
+fp8_config:
+ amax_compute_algo: max
+ amax_history_len: 1024
+ backend: TE
+ fp8_format: HYBRID
+ interval: 1
+ margin: 0
+ override_linear_precision: (false, false, false)
+ use_autocast_during_eval: false
+```
+
+## Configuring MS-AMP
+
+Of the two, `MS-AMP` is traditionally the easier one to configure as there is only a single argument: the optimization level.
+
+Currently two levels of optimization are supported in the Accelerate integration, `"O1"` and `"O2"` (using the letter 'o', not zero).
+
+* `"O1"` will cast the weight gradients and `all_reduce` communications to happen in 8-bit, while the rest are done in 16 bit. This reduces the general GPU memory usage and speeds up communication bandwidths.
+* `"O2"` will also cast first-order optimizer states into 8 bit, while the second order states are in FP16. (Currently just the `Adam` optimizer is supported). This tries its best to minimize final accuracy degradation and will save the highest potential memory.
+
+To specify an optimization level, pass it to the `FP8KwargsHandler` by setting the `optimization_level` argument:
+
+```{python}
+from accelerate import Accelerator
+from accelerate.utils import FP8RecipeKwargs
+kwargs = [FP8RecipeKwargs(backend="msamp", optimization_level="O2")]
+accelerator = Accelerator(mixed_precision="fp8", kwarg_handlers=kwargs)
+```
+
+Or during `accelerate launch` via `--fp8_backend=msamp --fp8_opt_level=O2`
+
+Similarly this can be set in your `config.yaml`:
+
+```{yaml}
+mixed_precision: fp8
+fp8_config:
+ backend: MSAMP
+ opt_level: O2
+```
+
+## Configuring TransformersEngine
+
+TransformersEngine has many options for customizing how and what FP8 calculations are performed. A full list of supported arguments and what they mean are available in [NVIDIA's documentation](https://docs.nvidia.com/deeplearning/transformer-engine/user-guide/api/common.html), however they are restated as part of [`FP8KwargsHandler`]'s docstring for your convenience.
+
+Accelerate tries to set sensible defaults, but exploring and tweaking the various parameters yourself can lead to better performance potentially.
+
+To use it, specify `backend="te"` and modify any of the arguments you want as part of your kwarg handler:
+
+```{python}
+from accelerate import Accelerator
+from accelerate.utils import FP8RecipeKwargs
+kwargs = [FP8RecipeKwargs(backend="te", ...)]
+accelerator = Accelerator(mixed_precision="fp8", kwarg_handlers=kwargs)
+```
+
+Or during `accelerate launch` via `--fp8_backend=te ...`. Use `accelerate launch --fp8_backend=te -h` to see relevent arguments.
+
+Similarly this can be set in your `config.yaml`:
+
+```{yaml}
+mixed_precision: fp8
+fp8_config:
+ amax_compute_algo: max
+ amax_history_len: 1024
+ backend: TE
+ fp8_format: HYBRID
+ interval: 1
+ margin: 0
+ override_linear_precision: (false, false, false)
+ use_autocast_during_eval: false
+```
+
+## Configuring `torchao`
+
+`torchao` is a [PyTorch-driven](https://github.com/pytorch/ao/tree/main/torchao/float8) hackable FP8 backend, aiming to be more approchable than the prior two engines. One of the core differences with `ao` compared to the prior two is that for numerical stability, it's found to be generally better off keeping the first *and* last layers in the model at the regular precision (be it FP32 or BF16), and then the other layers quantized down to FP8. As a result, a config for `ao` looks a bit differently:
+
+> Note: this API is experimental and is subject to change
+
+```{python}
+from accelerate import Accelerator
+from accelerate.utils import AORecipeKwargs
+kwargs = [AORecipeKwargs()]
+accelerator = Accelerator(mixed_precision="fp8", kwarg_handlers=kwargs)
+```
+
+To learn more about the specific parameters to be used, please see the official `torchao` repo.
+
+
+## Example Zoo
+
+We have examples showcasing training with FP8 both with accelerate and its underlying implementation available in the accelerate repo.
+Currently we support scripts showcasing:
+
+* Single GPU
+* Distributed Data Parallelism (Multi-GPU)
+* Fully Sharded Data Parallelism
+* DeepSpeed ZeRO 1 through 3
+
+Find out more [here](https://github.com/huggingface/accelerate/tree/main/benchmarks/fp8)
+
+## Further Reading
+
+To learn more about training in FP8 please check out the following resources:
+
+* [Our concept guide](../concept_guides/low_precision_training) detailing into more about both TransformersEngine and MS-AMP
+* [The `transformers-engine` documentation](https://docs.nvidia.com/deeplearning/transformer-engine/user-guide/api/common.html)
+* [The `MS-AMP` documentation](https://azure.github.io/MS-AMP/docs/)
+* [The `torchao` documentation](https://github.com/pytorch/ao/tree/main/torchao/float8)
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/megatron_lm.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/megatron_lm.md
new file mode 100644
index 0000000000000000000000000000000000000000..fb122b95ac5c13ddc78faef86e0f11e9441ee8ae
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/megatron_lm.md
@@ -0,0 +1,586 @@
+
+
+
+# Megatron-LM
+
+[Megatron-LM](https://github.com/NVIDIA/Megatron-LM) enables training large transformer language models at scale.
+It provides efficient tensor, pipeline and sequence based model parallelism for pre-training transformer based
+Language Models such as [GPT](https://huggingface.co/papers/2005.14165) (Decoder Only), [BERT](https://huggingface.co/papers/1810.04805) (Encoder Only) and [T5](https://huggingface.co/papers/1910.10683) (Encoder-Decoder).
+For detailed information and how things work behind the scene please refer to the github [repo](https://github.com/NVIDIA/Megatron-LM).
+
+## What is integrated?
+
+Accelerate integrates following feature of Megatron-LM to enable large scale pre-training/finetuning
+of BERT (Encoder), GPT (Decoder) or T5 models (Encoder and Decoder):
+
+a. **Tensor Parallelism (TP)**: Reduces memory footprint without much additional communication on intra-node ranks.
+Each tensor is split into multiple chunks with each shard residing on separate GPU. At each step, the same mini-batch of data is processed
+independently and in parallel by each shard followed by syncing across all GPUs (`all-reduce` operation).
+In a simple transformer layer, this leads to 2 `all-reduces` in the forward path and 2 in the backward path.
+For more details, please refer to the research paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using
+Model Parallelism](https://huggingface.co/papers/1909.08053) and
+this section of blogpost [The Technology Behind BLOOM Training](https://huggingface.co/blog/bloom-megatron-deepspeed#tensor-parallelism).
+
+
+b. **Pipeline Parallelism (PP)**: Reduces memory footprint and enables large scale training via inter-node parallelization.
+Reduces the bubble of naive PP via PipeDream-Flush schedule/1F1B schedule and Interleaved 1F1B schedule.
+Layers are distributed uniformly across PP stages. For example, if a model has `24` layers and we have `4` GPUs for
+pipeline parallelism, each GPU will have `6` layers (24/4). For more details on schedules to reduce the idle time of PP,
+please refer to the research paper [Efficient Large-Scale Language Model Training on GPU Clusters
+Using Megatron-LM](https://huggingface.co/papers/2104.04473) and
+this section of blogpost [The Technology Behind BLOOM Training](https://huggingface.co/blog/bloom-megatron-deepspeed#pipeline-parallelism).
+
+c. **Sequence Parallelism (SP)**: Reduces memory footprint without any additional communication. Only applicable when using TP.
+It reduces activation memory required as it prevents the same copies to be on the tensor parallel ranks
+post `all-reduce` by replacing them with `reduce-scatter` and `no-op` operation would be replaced by `all-gather`.
+As `all-reduce = reduce-scatter + all-gather`, this saves a ton of activation memory at no added communication cost.
+To put it simply, it shards the outputs of each transformer layer along sequence dimension, e.g.,
+if the sequence length is `1024` and the TP size is `4`, each GPU will have `256` tokens (1024/4) for each sample.
+This increases the batch size that can be supported for training. For more details, please refer to the research paper
+[Reducing Activation Recomputation in Large Transformer Models](https://huggingface.co/papers/2205.05198).
+
+d. **Data Parallelism (DP)** via Distributed Optimizer: Reduces the memory footprint by sharding optimizer states and gradients across DP ranks
+(versus the traditional method of replicating the optimizer state across data parallel ranks).
+For example, when using Adam optimizer with mixed-precision training, each parameter accounts for 12 bytes of memory.
+This gets distributed equally across the GPUs, i.e., each parameter would account for 3 bytes (12/4) if we have 4 GPUs.
+For more details, please refer to the research paper [ZeRO: Memory Optimizations Toward Training Trillion
+Parameter Models](https://huggingface.co/papers/1910.02054) and following section of blog
+[The Technology Behind BLOOM Training](https://huggingface.co/blog/bloom-megatron-deepspeed#zero-data-parallelism).
+
+e. **Selective Activation Recomputation**: Reduces the memory footprint of activations significantly via smart activation checkpointing.
+It doesn't store activations occupying large memory while being fast to recompute thereby achieving great tradeoff between memory and recomputation.
+For example, for GPT-3, this leads to 70% reduction in required memory for activations at the expense of
+only 2.7% FLOPs overhead for recomputation of activations. For more details, please refer to the research paper
+[Reducing Activation Recomputation in Large Transformer Models](https://huggingface.co/papers/2205.05198).
+
+f. **Fused Kernels**: Fused Softmax, Mixed Precision Fused Layer Norm and Fused gradient accumulation to weight gradient computation of linear layer.
+PyTorch JIT compiled Fused GeLU and Fused Bias+Dropout+Residual addition.
+
+g. **Support for Indexed datasets**: Efficient binary format of datasets for large scale training. Support for the `mmap`, `cached` index file and the `lazy` loader format.
+
+h. **Checkpoint reshaping and interoperability**: Utility for reshaping Megatron-LM checkpoints of variable
+tensor and pipeline parallel sizes to the beloved Transformers sharded checkpoints as it has great support with plethora of tools
+such as Accelerate Big Model Inference, Megatron-DeepSpeed Inference etc.
+Support is also available for converting Transformers sharded checkpoints to Megatron-LM checkpoint of variable tensor and pipeline parallel sizes
+for large scale training.
+
+
+## Pre-Requisites
+
+You will need to install the latest pytorch, cuda, nccl, and NVIDIA [APEX](https://github.com/NVIDIA/apex#quick-start) releases and the nltk library.
+See [documentation](https://github.com/NVIDIA/Megatron-LM#setup) for more details.
+Another way to setup the environment is to pull an NVIDIA PyTorch Container that comes with all the required installations from NGC.
+
+Below is a step-by-step method to set up the conda environment:
+
+1. Create a virtual environment
+```
+conda create --name ml
+```
+
+2. Assuming that the machine has CUDA 11.3 installed, installing the corresponding PyTorch GPU Version
+```
+conda install pytorch torchvision torchaudio cudatoolkit=11.3 -c pytorch
+```
+
+3. Install Nvidia APEX
+```
+git clone https://github.com/NVIDIA/apex
+cd apex
+pip install -v --disable-pip-version-check --no-cache-dir --global-option="--cpp_ext" --global-option="--cuda_ext" ./
+cd ..
+```
+
+4. Installing Megatron-LM
+
+```
+git clone https://github.com/NVIDIA/Megatron-LM.git
+cd Megatron-LM
+git checkout core_r0.5.0
+pip install --no-use-pep517 -e .
+```
+
+## Accelerate Megatron-LM Plugin
+
+Important features are directly supported via the `accelerate config` command.
+An example of the corresponding questions for using Megatron-LM features is shown below:
+
+```bash
+:~$ accelerate config --config_file "megatron_gpt_config.yaml"
+In which compute environment are you running? ([0] This machine, [1] AWS (Amazon SageMaker)): 0
+Which type of machine are you using? ([0] No distributed training, [1] multi-CPU, [2] multi-GPU, [3] TPU): 2
+How many different machines will you use (use more than 1 for multi-node training)? [1]:
+Do you want to use DeepSpeed? [yes/NO]:
+Do you want to use FullyShardedDataParallel? [yes/NO]:
+Do you want to use Megatron-LM ? [yes/NO]: yes
+What is the Tensor Parallelism degree/size? [1]:2
+Do you want to enable Sequence Parallelism? [YES/no]:
+What is the Pipeline Parallelism degree/size? [1]:2
+What is the number of micro-batches? [1]:2
+Do you want to enable selective activation recomputation? [YES/no]:
+Do you want to use distributed optimizer which shards optimizer state and gradients across data parallel ranks? [YES/no]:
+What is the gradient clipping value based on global L2 Norm (0 to disable)? [1.0]:
+How many GPU(s) should be used for distributed training? [1]:4
+Do you wish to use FP16 or BF16 (mixed precision)? [NO/fp16/bf16]: bf16
+```
+
+The resulting config is shown below:
+
+```
+~$ cat megatron_gpt_config.yaml
+compute_environment: LOCAL_MACHINE
+deepspeed_config: {}
+distributed_type: MEGATRON_LM
+downcast_bf16: 'no'
+fsdp_config: {}
+machine_rank: 0
+main_process_ip: null
+main_process_port: null
+main_training_function: main
+megatron_lm_config:
+ megatron_lm_gradient_clipping: 1.0
+ megatron_lm_num_micro_batches: 2
+ megatron_lm_pp_degree: 2
+ megatron_lm_recompute_activations: true
+ megatron_lm_sequence_parallelism: true
+ megatron_lm_tp_degree: 2
+ megatron_lm_use_distributed_optimizer: true
+mixed_precision: bf16
+num_machines: 1
+num_processes: 4
+rdzv_backend: static
+same_network: true
+use_cpu: false
+```
+
+We will take the example of GPT pre-training. The minimal changes required to the official `run_clm_no_trainer.py`
+to use Megatron-LM are as follows:
+
+1. As Megatron-LM uses its own implementation of Optimizer, the corresponding scheduler compatible with it needs to be used.
+As such, support for only the Megatron-LM's scheduler is present. User will need to create `accelerate.utils.MegatronLMDummyScheduler`.
+Example is given below:
+
+```python
+from accelerate.utils import MegatronLMDummyScheduler
+
+if accelerator.distributed_type == DistributedType.MEGATRON_LM:
+ lr_scheduler = MegatronLMDummyScheduler(
+ optimizer=optimizer,
+ total_num_steps=args.max_train_steps,
+ warmup_num_steps=args.num_warmup_steps,
+ )
+else:
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps * args.gradient_accumulation_steps,
+ num_training_steps=args.max_train_steps * args.gradient_accumulation_steps,
+ )
+```
+
+2. Getting the details of the total batch size now needs to be cognization of tensor and pipeline parallel sizes.
+Example of getting the effective total batch size is shown below:
+
+```python
+if accelerator.distributed_type == DistributedType.MEGATRON_LM:
+ total_batch_size = accelerator.state.megatron_lm_plugin.global_batch_size
+else:
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+```
+
+3. When using Megatron-LM, the losses are already averaged across the data parallel group
+
+```python
+if accelerator.distributed_type == DistributedType.MEGATRON_LM:
+ losses.append(loss)
+else:
+ losses.append(accelerator.gather_for_metrics(loss.repeat(args.per_device_eval_batch_size)))
+
+if accelerator.distributed_type == DistributedType.MEGATRON_LM:
+ losses = torch.tensor(losses)
+else:
+ losses = torch.cat(losses)
+```
+
+4. For Megatron-LM, we need to save the model using `accelerator.save_state`
+
+```python
+if accelerator.distributed_type == DistributedType.MEGATRON_LM:
+ accelerator.save_state(args.output_dir)
+else:
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+```
+
+That's it! We are good to go 🚀. Please find the example script in the examples folder at the path `accelerate/examples/by_feature/megatron_lm_gpt_pretraining.py`.
+Let's run it for `gpt-large` model architecture using 4 A100-80GB GPUs.
+
+```bash
+accelerate launch --config_file megatron_gpt_config.yaml \
+examples/by_feature/megatron_lm_gpt_pretraining.py \
+--config_name "gpt2-large" \
+--tokenizer_name "gpt2-large" \
+--dataset_name wikitext \
+--dataset_config_name wikitext-2-raw-v1 \
+--block_size 1024 \
+--learning_rate 5e-5 \
+--per_device_train_batch_size 24 \
+--per_device_eval_batch_size 24 \
+--num_train_epochs 5 \
+--with_tracking \
+--report_to "wandb" \
+--output_dir "awesome_model"
+```
+
+Below are some important excerpts from the output logs:
+
+```bash
+Loading extension module fused_dense_cuda...
+>>> done with compiling and loading fused kernels. Compilation time: 3.569 seconds
+ > padded vocab (size: 50257) with 175 dummy tokens (new size: 50432)
+Building gpt model in the pre-training mode.
+The Megatron LM model weights are initialized at random in `accelerator.prepare`. Please use `accelerator.load_checkpoint` to load a pre-trained checkpoint matching the distributed setup.
+Preparing dataloader
+Preparing dataloader
+Preparing model
+ > number of parameters on (tensor, pipeline) model parallel rank (1, 0): 210753280
+ > number of parameters on (tensor, pipeline) model parallel rank (1, 1): 209445120
+ > number of parameters on (tensor, pipeline) model parallel rank (0, 0): 210753280
+ > number of parameters on (tensor, pipeline) model parallel rank (0, 1): 209445120
+Preparing optimizer
+Preparing scheduler
+> learning rate decay style: linear
+10/10/2022 22:57:22 - INFO - __main__ - ***** Running training *****
+10/10/2022 22:57:22 - INFO - __main__ - Num examples = 2318
+10/10/2022 22:57:22 - INFO - __main__ - Num Epochs = 5
+10/10/2022 22:57:22 - INFO - __main__ - Instantaneous batch size per device = 24
+10/10/2022 22:57:22 - INFO - __main__ - Total train batch size (w. parallel, distributed & accumulation) = 48
+10/10/2022 22:57:22 - INFO - __main__ - Gradient Accumulation steps = 1
+10/10/2022 22:57:22 - INFO - __main__ - Total optimization steps = 245
+ 20%|████████████▍ | 49/245 [01:04<04:09, 1.27s/it]
+ 10/10/2022 22:58:29 - INFO - __main__ - epoch 0: perplexity: 1222.1594275215962 eval_loss: 7.10837459564209
+ 40%|████████████████████████▊ | 98/245 [02:10<03:07, 1.28s/it]
+ 10/10/2022 22:59:35 - INFO - __main__ - epoch 1: perplexity: 894.5236583794557 eval_loss: 6.796291351318359
+ 60%|████████████████████████████████████▌ | 147/245 [03:16<02:05, 1.28s/it]
+ 10/10/2022 23:00:40 - INFO - __main__ - epoch 2: perplexity: 702.8458788508042 eval_loss: 6.555137634277344
+ 80%|████████████████████████████████████████████████▊ | 196/245 [04:22<01:02, 1.28s/it]
+ 10/10/2022 23:01:46 - INFO - __main__ - epoch 3: perplexity: 600.3220028695281 eval_loss: 6.39746618270874
+100%|█████████████████████████████████████████████████████████████| 245/245 [05:27<00:00, 1.28s/it]
+```
+
+There are a large number of other options/features that one can set using `accelerate.utils.MegatronLMPlugin`.
+
+## Advanced features to leverage writing custom train step and Megatron-LM Indexed Datasets
+
+For leveraging more features, please go through below details.
+
+1. Below is an example of changes required to customize the Train Step while using Megatron-LM.
+You will implement the `accelerate.utils.AbstractTrainStep` or inherit from their corresponding children
+`accelerate.utils.GPTTrainStep`, `accelerate.utils.BertTrainStep` or `accelerate.utils.T5TrainStep`.
+
+```python
+from accelerate.utils import MegatronLMDummyScheduler, GPTTrainStep, avg_losses_across_data_parallel_group
+
+
+# Custom loss function for the Megatron model
+class GPTTrainStepWithCustomLoss(GPTTrainStep):
+ def __init__(self, megatron_args, **kwargs):
+ super().__init__(megatron_args)
+ self.kwargs = kwargs
+
+ def get_loss_func(self):
+ def loss_func(inputs, loss_mask, output_tensor):
+ batch_size, seq_length = output_tensor.shape
+ losses = output_tensor.float()
+ loss_mask = loss_mask.view(-1).float()
+ loss = losses.view(-1) * loss_mask
+
+ # Resize and average loss per sample
+ loss_per_sample = loss.view(batch_size, seq_length).sum(axis=1)
+ loss_mask_per_sample = loss_mask.view(batch_size, seq_length).sum(axis=1)
+ loss_per_sample = loss_per_sample / loss_mask_per_sample
+
+ # Calculate and scale weighting
+ weights = torch.stack([(inputs == kt).float() for kt in self.kwargs["keytoken_ids"]]).sum(axis=[0, 2])
+ weights = 1.0 + self.kwargs["alpha"] * weights
+ # Calculate weighted average
+ weighted_loss = (loss_per_sample * weights).mean()
+
+ # Reduce loss across data parallel groups
+ averaged_loss = avg_losses_across_data_parallel_group([weighted_loss])
+
+ return weighted_loss, {"lm loss": averaged_loss[0]}
+
+ return loss_func
+
+ def get_forward_step_func(self):
+ def forward_step(data_iterator, model):
+ """Forward step."""
+ # Get the batch.
+ tokens, labels, loss_mask, attention_mask, position_ids = self.get_batch(data_iterator)
+ output_tensor = model(tokens, position_ids, attention_mask, labels=labels)
+
+ return output_tensor, partial(self.loss_func, tokens, loss_mask)
+
+ return forward_step
+
+
+def main():
+ # Custom loss function for the Megatron model
+ keytoken_ids = []
+ keywords = ["plt", "pd", "sk", "fit", "predict", " plt", " pd", " sk", " fit", " predict"]
+ for keyword in keywords:
+ ids = tokenizer([keyword]).input_ids[0]
+ if len(ids) == 1:
+ keytoken_ids.append(ids[0])
+ accelerator.print(f"Keytoken ids: {keytoken_ids}")
+ accelerator.state.megatron_lm_plugin.custom_train_step_class = GPTTrainStepWithCustomLoss
+ accelerator.state.megatron_lm_plugin.custom_train_step_kwargs = {
+ "keytoken_ids": keytoken_ids,
+ "alpha": 0.25,
+ }
+```
+
+2. For using the Megatron-LM datasets, a few more changes are required. Dataloaders for these datasets
+are available only on rank 0 of each tensor parallel group. As such, there are rank where dataloader won't be
+available and this requires tweaks to the training loop. Being able to do all this shows how
+flexible and extensible Accelerate is. The changes required are as follows.
+
+a. For Megatron-LM indexed datasets, we need to use `MegatronLMDummyDataLoader`
+and pass the required dataset args to it such as `data_path`, `seq_length` etc.
+See [here](https://github.com/NVIDIA/Megatron-LM/blob/main/megatron/arguments.py#L804) for the list of available args.
+
+```python
+from accelerate.utils import MegatronLMDummyDataLoader
+
+megatron_dataloader_config = {
+ "data_path": args.data_path,
+ "splits_string": args.splits_string,
+ "seq_length": args.block_size,
+ "micro_batch_size": args.per_device_train_batch_size,
+}
+megatron_dataloader = MegatronLMDummyDataLoader(**megatron_dataloader_config)
+accelerator.state.megatron_lm_plugin.megatron_dataset_flag = True
+```
+
+b. `megatron_dataloader` is repeated 3 times to get training, validation and test dataloaders
+as per the `args.splits_string` proportions
+
+```python
+model, optimizer, lr_scheduler, train_dataloader, eval_dataloader, _ = accelerator.prepare(
+ model, optimizer, lr_scheduler, megatron_dataloader, megatron_dataloader, megatron_dataloader
+)
+```
+
+c. Changes to training and evaluation loops as dataloader is only available on tensor parallel ranks 0
+So, we need to iterate only if the dataloader isn't `None` else provide empty dict
+As such, we loop using `while` loop and break when `completed_steps` is equal to `args.max_train_steps`
+This is similar to the Megatron-LM setup wherein user has to provide `max_train_steps` when using Megaton-LM indexed datasets.
+This displays how flexible and extensible Accelerate is.
+
+```python
+while completed_steps < args.max_train_steps:
+ model.train()
+ batch = next(train_dataloader) if train_dataloader is not None else {}
+ outputs = model(**batch)
+ loss = outputs.loss
+ ...
+
+ if completed_steps % eval_interval == 0:
+ eval_completed_steps = 0
+ losses = []
+ while eval_completed_steps < eval_iters:
+ model.eval()
+ with torch.no_grad():
+ batch = next(eval_dataloader) if eval_dataloader is not None else {}
+ outputs = model(**batch)
+```
+
+
+## Utility for Checkpoint reshaping and interoperability
+
+1. The scripts for these are present in Transformers library under respective models.
+Currently, it is available for GPT model [checkpoint_reshaping_and_interoperability.py](https://github.com/huggingface/transformers/blob/main/src/transformers/models/megatron_gpt2/checkpoint_reshaping_and_interoperability.py)
+
+2. Below is an example of conversion of checkpoint from Megatron-LM to universal Transformers sharded checkpoint.
+```bash
+python checkpoint_reshaping_and_interoperability.py \
+--convert_checkpoint_from_megatron_to_transformers \
+--load_path "gpt/iter_0005000" \
+--save_path "gpt/trfs_checkpoint" \
+--max_shard_size "200MB" \
+--tokenizer_name "gpt2" \
+--print-checkpoint-structure
+```
+
+3. Conversion of checkpoint from transformers to megatron with `tp_size=2`, `pp_size=2` and `dp_size=2`.
+```bash
+python checkpoint_utils/megatgron_gpt2/checkpoint_reshaping_and_interoperability.py \
+--load_path "gpt/trfs_checkpoint" \
+--save_path "gpt/megatron_lm_checkpoint" \
+--target_tensor_model_parallel_size 2 \
+--target_pipeline_model_parallel_size 2 \
+--target_data_parallel_size 2 \
+--target_params_dtype "bf16" \
+--make_vocab_size_divisible_by 128 \
+--use_distributed_optimizer \
+--print-checkpoint-structure
+```
+
+## Megatron-LM GPT models support returning logits and `megatron_generate` function for text generation
+
+1. Returning logits require setting `require_logits=True` in MegatronLMPlugin as shown below.
+These would be available in the last stage of pipeline.
+```python
+megatron_lm_plugin = MegatronLMPlugin(return_logits=True)
+```
+
+2. `megatron_generate` method for Megatron-LM GPT model: This will use Tensor and Pipeline Parallelism to complete
+generations for a batch of inputs when using greedy with/without top_k/top_p sampling and for individual prompt inputs when using beam search decoding.
+Only a subset of features of transformers generate is supported. This will help in using large models via tensor and pipeline parallelism
+for generation (already does key-value caching and uses fused kernels by default).
+This requires data parallel size to be 1, sequence parallelism and activation checkpointing to be disabled.
+It also requires specifying path to tokenizer's vocab file and merges file.
+Below example shows how to configure and use `megatron_generate` method for Megatron-LM GPT model.
+```python
+# specifying tokenizer's vocab and merges file
+vocab_file = os.path.join(args.resume_from_checkpoint, "vocab.json")
+merge_file = os.path.join(args.resume_from_checkpoint, "merges.txt")
+other_megatron_args = {"vocab_file": vocab_file, "merge_file": merge_file}
+megatron_lm_plugin = MegatronLMPlugin(other_megatron_args=other_megatron_args)
+
+# inference using `megatron_generate` functionality
+tokenizer.pad_token = tokenizer.eos_token
+max_new_tokens = 64
+batch_texts = [
+ "Are you human?",
+ "The purpose of life is",
+ "The arsenal was constructed at the request of",
+ "How are you doing these days?",
+]
+batch_encodings = tokenizer(batch_texts, return_tensors="pt", padding=True)
+
+# top-p sampling
+generated_tokens = model.megatron_generate(
+ batch_encodings["input_ids"],
+ batch_encodings["attention_mask"],
+ max_new_tokens=max_new_tokens,
+ top_p=0.8,
+ top_p_decay=0.5,
+ temperature=0.9,
+)
+decoded_preds = tokenizer.batch_decode(generated_tokens.cpu().numpy())
+accelerator.print(decoded_preds)
+
+# top-k sampling
+generated_tokens = model.megatron_generate(
+ batch_encodings["input_ids"],
+ batch_encodings["attention_mask"],
+ max_new_tokens=max_new_tokens,
+ top_k=50,
+ temperature=0.9,
+)
+decoded_preds = tokenizer.batch_decode(generated_tokens.cpu().numpy())
+accelerator.print(decoded_preds)
+
+# adding `bos` token at the start
+generated_tokens = model.megatron_generate(
+ batch_encodings["input_ids"], batch_encodings["attention_mask"], max_new_tokens=max_new_tokens, add_BOS=True
+)
+decoded_preds = tokenizer.batch_decode(generated_tokens.cpu().numpy())
+accelerator.print(decoded_preds)
+
+# beam search => only takes single prompt
+batch_texts = ["The purpose of life is"]
+batch_encodings = tokenizer(batch_texts, return_tensors="pt", padding=True)
+generated_tokens = model.megatron_generate(
+ batch_encodings["input_ids"],
+ batch_encodings["attention_mask"],
+ max_new_tokens=max_new_tokens,
+ num_beams=20,
+ length_penalty=1.5,
+)
+decoded_preds = tokenizer.batch_decode(generated_tokens.cpu().numpy())
+accelerator.print(decoded_preds)
+```
+
+3. An end-to-end example of using `megatron_generate` method for Megatron-LM GPT model is available at
+[megatron_gpt2_generation.py](https://github.com/pacman100/accelerate-megatron-test/blob/main/src/inference/megatron_gpt2_generation.py) with
+config file [megatron_lm_gpt_generate_config.yaml](https://github.com/pacman100/accelerate-megatron-test/blob/main/src/Configs/megatron_lm_gpt_generate_config.yaml).
+The bash script with accelerate launch command is available at [megatron_lm_gpt_generate.sh](https://github.com/pacman100/accelerate-megatron-test/blob/main/megatron_lm_gpt_generate.sh).
+The output logs of the script are available at [megatron_lm_gpt_generate.log](https://github.com/pacman100/accelerate-megatron-test/blob/main/output_logs/megatron_lm_gpt_generate.log).
+
+## Support for ROPE and ALiBi Positional embeddings and Multi-Query Attention
+
+1. For ROPE/ALiBi attention, pass `position_embedding_type` with `("absolute" | "rotary" | "alibi")` to `MegatronLMPlugin` as shown below.
+```python
+other_megatron_args = {"position_embedding_type": "alibi"}
+megatron_lm_plugin = MegatronLMPlugin(other_megatron_args=other_megatron_args)
+```
+
+2. For Multi-Query Attention, pass `attention_head_type` with `("multihead" | "multiquery")` to `MegatronLMPlugin` as shown below.
+```python
+other_megatron_args = {"attention_head_type": "multiquery"}
+megatron_lm_plugin = MegatronLMPlugin(other_megatron_args=other_megatron_args)
+```
+
+## Caveats
+
+1. Supports Transformers GPT2, Megatron-BERT and T5 models.
+This covers Decoder only, Encode only and Encoder-Decoder model classes.
+
+2. Only loss is returned from model forward pass as
+there is quite complex interplay of pipeline, tensor and data parallelism behind the scenes.
+The `model(**batch_data)` call return loss(es) averaged across the data parallel ranks.
+This is fine for most cases wherein pre-training jobs are run using Megatron-LM features and
+you can easily compute the `perplexity` using the loss.
+For GPT model, returning logits in addition to loss(es) is supported.
+These logits aren't gathered across data parallel ranks. Use `accelerator.utils.gather_across_data_parallel_groups`
+to gather logits across data parallel ranks. These logits along with labels can be used for computing various
+performance metrics.
+
+3. The main process is the last rank as the losses/logits are available in the last stage of pipeline.
+`accelerator.is_main_process` and `accelerator.is_local_main_process` return `True` for last rank when using
+Megatron-LM integration.
+
+4. In `accelerator.prepare` call, a Megatron-LM model corresponding to a given Transformers model is created
+with random weights. Please use `accelerator.load_state` to load the Megatron-LM checkpoint with matching TP, PP and DP partitions.
+
+5. Currently, checkpoint reshaping and interoperability support is only available for GPT.
+Soon it will be extended to BERT and T5.
+
+6. `gradient_accumulation_steps` needs to be 1. When using Megatron-LM, micro batches in pipeline parallelism
+setting is synonymous with gradient accumulation.
+
+7. When using Megatron-LM, use `accelerator.save_state` and `accelerator.load_state` for saving and loading checkpoints.
+
+8. Below are the mapping from Megatron-LM model architectures to the equivalent transformers model architectures.
+Only these transformers model architectures are supported.
+
+a. Megatron-LM [BertModel](https://github.com/NVIDIA/Megatron-LM/blob/main/megatron/model/bert_model.py) :
+transformers models with `megatron-bert` in config's model type, e.g.,
+[MegatronBERT](https://huggingface.co/docs/transformers/model_doc/megatron-bert)
+
+b. Megatron-LM [GPTModel](https://github.com/NVIDIA/Megatron-LM/blob/main/megatron/model/gpt_model.py) :
+transformers models with `gpt2` in config's model type, e.g.,
+[OpenAI GPT2](https://huggingface.co/docs/transformers/model_doc/gpt2)
+
+c. Megatron-LM [T5Model](https://github.com/NVIDIA/Megatron-LM/blob/main/megatron/model/t5_model.py) :
+transformers models with `t5` in config's model type, e.g.,
+[T5](https://huggingface.co/docs/transformers/model_doc/t5) and
+[MT5](https://huggingface.co/docs/transformers/model_doc/mt5)
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/model_size_estimator.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/model_size_estimator.md
new file mode 100644
index 0000000000000000000000000000000000000000..7ce67f56a4a8ecfa77fcc047237e8e0d96f6f30d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/model_size_estimator.md
@@ -0,0 +1,137 @@
+
+
+# Model memory estimator
+
+One very difficult aspect when exploring potential models to use on your machine is knowing just how big of a model will *fit* into memory with your current graphics card (such as loading the model onto CUDA).
+
+To help alleviate this, Accelerate has a CLI interface through `accelerate estimate-memory`. This tutorial will
+help walk you through using it, what to expect, and at the end link to the interactive demo hosted on the Hub which will
+even let you post those results directly on the model repo!
+
+Currently we support searching for models that can be used in `timm` and `transformers`.
+
+
+
+ This API will load the model into memory on the `meta` device, so we are not actually downloading
+ and loading the full weights of the model into memory, nor do we need to. As a result it's
+ perfectly fine to measure 8 billion parameter models (or more), without having to worry about
+ if your CPU can handle it!
+
+
+
+## Gradio Demos
+
+Below are a few gradio demos related to what was described above. The first is the official Hugging Face memory estimation space, utilizing Accelerate directly:
+
+
+
+
+
+
+
+
+A community member has taken the idea and expanded it further, allowing you to filter models directly and see if you can run a particular LLM given GPU constraints and LoRA configurations. To play with it, see [here](https://huggingface.co/spaces/Vokturz/can-it-run-llm) for more details.
+
+## The Command
+
+When using `accelerate estimate-memory`, you need to pass in the name of the model you want to use, potentially the framework
+that model utilizing (if it can't be found automatically), and the data types you want the model to be loaded in with.
+
+For example, here is how we can calculate the memory footprint for `bert-base-cased`:
+
+```bash
+accelerate estimate-memory bert-base-cased
+```
+
+This will download the `config.json` for `bert-based-cased`, load the model on the `meta` device, and report back how much space
+it will use:
+
+Memory Usage for loading `bert-base-cased`:
+
+| dtype | Largest Layer | Total Size | Training using Adam |
+|---------|---------------|------------|---------------------|
+| float32 | 84.95 MB | 418.18 MB | 1.61 GB |
+| float16 | 42.47 MB | 206.59 MB | 826.36 MB |
+| int8 | 21.24 MB | 103.29 MB | 413.18 MB |
+| int4 | 10.62 MB | 51.65 MB | 206.59 MB |
+
+By default it will return all the supported dtypes (`int4` through `float32`), but if you are interested in specific ones these can be filtered.
+
+### Specific libraries
+
+If the source library cannot be determined automatically (like it could in the case of `bert-base-cased`), a library name can
+be passed in.
+
+```bash
+accelerate estimate-memory HuggingFaceM4/idefics-80b-instruct --library_name transformers
+```
+
+Memory Usage for loading `HuggingFaceM4/idefics-80b-instruct`:
+
+| dtype | Largest Layer | Total Size | Training using Adam |
+|---------|---------------|------------|---------------------|
+| float32 | 3.02 GB | 297.12 GB | 1.16 TB |
+| float16 | 1.51 GB | 148.56 GB | 594.24 GB |
+| int8 | 772.52 MB | 74.28 GB | 297.12 GB |
+| int4 | 386.26 MB | 37.14 GB | 148.56 GB |
+
+
+```bash
+accelerate estimate-memory timm/resnet50.a1_in1k --library_name timm
+```
+
+Memory Usage for loading `timm/resnet50.a1_in1k`:
+
+| dtype | Largest Layer | Total Size | Training using Adam |
+|---------|---------------|------------|---------------------|
+| float32 | 9.0 MB | 97.7 MB | 390.78 MB |
+| float16 | 4.5 MB | 48.85 MB | 195.39 MB |
+| int8 | 2.25 MB | 24.42 MB | 97.7 MB |
+| int4 | 1.12 MB | 12.21 MB | 48.85 MB |
+
+### Specific dtypes
+
+As mentioned earlier, while we return `int4` through `float32` by default, any dtype can be used from `float32`, `float16`, `int8`, and `int4`.
+
+To do so, pass them in after specifying `--dtypes`:
+
+```bash
+accelerate estimate-memory bert-base-cased --dtypes float32 float16
+```
+
+Memory Usage for loading `bert-base-cased`:
+
+| dtype | Largest Layer | Total Size | Training using Adam |
+|---------|---------------|------------|---------------------|
+| float32 | 84.95 MB | 413.18 MB | 1.61 GB |
+| float16 | 42.47 MB | 206.59 MB | 826.36 MB |
+
+## Caveats with this calculator
+
+This calculator will tell you how much memory is needed to purely load the model in, *not* to perform inference.
+
+This calculation is accurate within a few % of the actual value, so it is a very good view of just how much memory it will take. For instance loading `bert-base-cased` actually takes `413.68 MB` when loaded on CUDA in full precision, and the calculator estimates `413.18 MB`.
+
+When performing inference you can expect to add up to an additional 20% as found by [EleutherAI](https://blog.eleuther.ai/transformer-math/). We'll be conducting research into finding a more accurate estimate to these values, and will update
+this calculator once done.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/mps.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/mps.md
new file mode 100644
index 0000000000000000000000000000000000000000..8a18d7dc8e6d5646b77479dea010526b3addc90c
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/mps.md
@@ -0,0 +1,51 @@
+
+
+# Accelerated PyTorch Training on Mac
+
+With PyTorch v1.12 release, developers and researchers can take advantage of Apple silicon GPUs for significantly faster model training.
+This unlocks the ability to perform machine learning workflows like prototyping and fine-tuning locally, right on Mac.
+Apple's Metal Performance Shaders (MPS) as a backend for PyTorch enables this and can be used via the new `"mps"` device.
+This will map computational graphs and primitives on the MPS Graph framework and tuned kernels provided by MPS.
+For more information please refer official documents [Introducing Accelerated PyTorch Training on Mac](https://pytorch.org/blog/introducing-accelerated-pytorch-training-on-mac/)
+and [MPS BACKEND](https://pytorch.org/docs/stable/notes/mps.html).
+
+### Benefits of Training and Inference using Apple Silicon Chips
+
+1. Enables users to train larger networks or batch sizes locally
+2. Reduces data retrieval latency and provides the GPU with direct access to the full memory store due to unified memory architecture.
+Therefore, improving end-to-end performance.
+3. Reduces costs associated with cloud-based development or the need for additional local GPUs.
+
+**Pre-requisites**: To install torch with mps support,
+please follow this nice medium article [GPU-Acceleration Comes to PyTorch on M1 Macs](https://medium.com/towards-data-science/gpu-acceleration-comes-to-pytorch-on-m1-macs-195c399efcc1).
+
+
+## How it works out of the box
+It is enabled by default on MacOs machines with MPS enabled Apple Silicon GPUs.
+To disable it, pass `--cpu` flag to `accelerate launch` command or answer the corresponding question when answering the `accelerate config` questionnaire.
+
+You can directly run the following script to test it out on MPS enabled Apple Silicon machines:
+```bash
+accelerate launch /examples/cv_example.py --data_dir images
+```
+
+## A few caveats to be aware of
+
+1. Distributed setups `gloo` and `nccl` are not working with `mps` device.
+This means that currently only single GPU of `mps` device type can be used.
+
+Finally, please, remember that, `Accelerate` only integrates MPS backend, therefore if you
+have any problems or questions with regards to MPS backend usage, please, file an issue with [PyTorch GitHub](https://github.com/pytorch/pytorch/issues).
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/profiler.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/profiler.md
new file mode 100644
index 0000000000000000000000000000000000000000..ddd7bd1885c4c93d8f330d29acad89b1dc7ac09d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/profiler.md
@@ -0,0 +1,337 @@
+
+
+# Profiler
+
+Profiler is a tool that allows the collection of performance metrics during training and inference. Profiler’s context manager API can be used to better understand what model operators are the most expensive, examine their input shapes and stack traces, study device kernel activity, and visualize the execution trace. It provides insights into the performance of your model, allowing you to optimize and improve it.
+
+This guide explains how to use PyTorch Profiler to measure the time and memory consumption of the model’s operators and how to integrate this with Accelerate. We will cover various use cases and provide examples for each.
+
+## Using profiler to analyze execution time
+
+Profiler allows one to check which operators were called during the execution of a code range wrapped with a profiler context manager.
+
+Let’s see how we can use profiler to analyze the execution time:
+
+
+
+
+```python
+import torch
+import torchvision.models as models
+from torch.profiler import profile, record_function, ProfilerActivity
+
+model = models.resnet18()
+inputs = torch.randn(5, 3, 224, 224)
+
+with profile(activities=[ProfilerActivity.CPU], record_shapes=True) as prof:
+ model(inputs)
+
+print(prof.key_averages().table(sort_by="cpu_time_total", row_limit=10))
+```
+
+
+
+
+```python
+from accelerate import Accelerator, ProfileKwargs
+import torch
+import torchvision.models as models
+
+model = models.resnet18()
+inputs = torch.randn(5, 3, 224, 224)
+
+profile_kwargs = ProfileKwargs(
+ activities=["cpu"],
+ record_shapes=True
+)
+
+accelerator = Accelerator(cpu=True, kwargs_handlers=[profile_kwargs])
+model = accelerator.prepare(model)
+
+with accelerator.profile() as prof:
+ with torch.no_grad():
+ model(inputs)
+
+print(prof.key_averages().table(sort_by="cpu_time_total", row_limit=10))
+```
+
+
+
+
+The resulting table output (omitting some columns):
+
+```
+--------------------------------- ------------ ------------ ------------ ------------
+ Name Self CPU CPU total CPU time avg # of Calls
+--------------------------------- ------------ ------------ ------------ ------------
+ aten::conv2d 171.000us 52.260ms 2.613ms 20
+ aten::convolution 227.000us 52.089ms 2.604ms 20
+ aten::_convolution 270.000us 51.862ms 2.593ms 20
+ aten::mkldnn_convolution 51.273ms 51.592ms 2.580ms 20
+ aten::batch_norm 118.000us 7.059ms 352.950us 20
+ aten::_batch_norm_impl_index 315.000us 6.941ms 347.050us 20
+ aten::native_batch_norm 6.305ms 6.599ms 329.950us 20
+ aten::max_pool2d 40.000us 4.008ms 4.008ms 1
+ aten::max_pool2d_with_indices 3.968ms 3.968ms 3.968ms 1
+ aten::add_ 780.000us 780.000us 27.857us 28
+--------------------------------- ------------ ------------ ------------ ------------
+Self CPU time total: 67.016ms
+```
+
+To get a finer granularity of results and include operator input shapes, pass `group_by_input_shape=True` (note: this requires running the profiler with `record_shapes=True`):
+
+```python
+print(prof.key_averages(group_by_input_shape=True).table(sort_by="cpu_time_total", row_limit=10))
+```
+
+## Using profiler to analyze memory consumption
+
+Profiler can also show the amount of memory (used by the model’s tensors) that was allocated (or released) during the execution of the model’s operators. To enable memory profiling functionality pass `profile_memory=True`.
+
+
+
+
+```python
+model = models.resnet18()
+inputs = torch.randn(5, 3, 224, 224)
+
+with profile(activities=[ProfilerActivity.CPU],
+ profile_memory=True, record_shapes=True) as prof:
+ model(inputs)
+
+print(prof.key_averages().table(sort_by="self_cpu_memory_usage", row_limit=10))
+```
+
+
+
+
+```python
+model = models.resnet18()
+inputs = torch.randn(5, 3, 224, 224)
+
+profile_kwargs = ProfileKwargs(
+ activities=["cpu"],
+ profile_memory=True,
+ record_shapes=True
+)
+
+accelerator = Accelerator(cpu=True, kwargs_handlers=[profile_kwargs])
+model = accelerator.prepare(model)
+
+with accelerator.profile() as prof:
+ model(inputs)
+
+print(prof.key_averages().table(sort_by="self_cpu_memory_usage", row_limit=10))
+```
+
+
+
+
+The resulting table output (omitting some columns):
+
+```
+--------------------------------- ------------ ------------ ------------
+ Name CPU Mem Self CPU Mem # of Calls
+--------------------------------- ------------ ------------ ------------
+ aten::empty 94.85 Mb 94.85 Mb 205
+ aten::max_pool2d_with_indices 11.48 Mb 11.48 Mb 1
+ aten::addmm 19.53 Kb 19.53 Kb 1
+ aten::mean 10.00 Kb 10.00 Kb 1
+ aten::empty_strided 492 b 492 b 5
+ aten::cat 240 b 240 b 6
+ aten::abs 480 b 240 b 4
+ aten::masked_select 120 b 112 b 1
+ aten::ne 61 b 53 b 3
+ aten::eq 30 b 30 b 1
+--------------------------------- ------------ ------------ ------------
+Self CPU time total: 69.332ms
+```
+
+
+## Exporting chrome trace
+
+You can examine the sequence of profiled operators and CUDA kernels in Chrome trace viewer (`chrome://tracing`):
+
+
+
+
+
+
+```python
+model = models.resnet18().cuda()
+inputs = torch.randn(5, 3, 224, 224).cuda()
+
+with profile(activities=[ProfilerActivity.CPU, ProfilerActivity.CUDA]) as prof:
+ model(inputs)
+
+prof.export_chrome_trace("trace.json")
+```
+
+
+
+
+```python
+model = models.resnet18()
+inputs = torch.randn(5, 3, 224, 224).cuda()
+profile_kwargs = ProfileKwargs(
+ activities=["cpu", "cuda"],
+ output_trace_dir="trace"
+)
+
+accelerator = Accelerator(kwargs_handlers=[profile_kwargs])
+model = accelerator.prepare(model)
+
+with accelerator.profile() as prof:
+ model(inputs)
+
+# The trace will be saved to the specified directory
+```
+For other hardware accelerators, e.g. XPU, you can change `cuda` to `xpu` in the above example code.
+
+
+
+
+## Using Profiler to Analyze Long-Running Jobs
+
+Profiler offers an additional API to handle long-running jobs (such as training loops). Tracing all of the execution can be slow and result in very large trace files. To avoid this, use optional arguments:
+
+- `schedule_option`: Scheduling options allow you to control when profiling is active. This is useful for long-running jobs to avoid collecting too much data. Available keys are `wait`, `warmup`, `active`, `repeat` and `skip_first`. The profiler will skip the first `skip_first` steps, then wait for `wait` steps, then do the warmup for the next `warmup` steps, then do the active recording for the next `active` steps and then repeat the cycle starting with `wait` steps. The optional number of cycles is specified with the `repeat` parameter, the zero value means that the cycles will continue until the profiling is finished.
+- `on_trace_ready`: specifies a function that takes a reference to the profiler as an input and is called by the profiler each time the new trace is ready.
+
+To illustrate how the API works, consider the following example:
+
+
+
+
+```python
+from torch.profiler import schedule
+
+my_schedule = schedule(
+ skip_first=1,
+ wait=5,
+ warmup=1,
+ active=3,
+ repeat=2
+)
+
+def trace_handler(p):
+ output = p.key_averages().table(sort_by="self_cuda_time_total", row_limit=10)
+ print(output)
+ p.export_chrome_trace("/tmp/trace_" + str(p.step_num) + ".json")
+
+with profile(
+ activities=[ProfilerActivity.CPU, ProfilerActivity.CUDA],
+ schedule=my_schedule,
+ on_trace_ready=trace_handler
+) as p:
+ for idx in range(8):
+ model(inputs)
+ p.step()
+```
+
+
+
+
+```python
+def trace_handler(p):
+ output = p.key_averages().table(sort_by="self_cuda_time_total", row_limit=10)
+ print(output)
+ p.export_chrome_trace("/tmp/trace_" + str(p.step_num) + ".json")
+
+profile_kwargs = ProfileKwargs(
+ activities=["cpu", "cuda"],
+ schedule_option={"wait": 5, "warmup": 1, "active": 3, "repeat": 2, "skip_first": 1},
+ on_trace_ready=trace_handler
+)
+
+accelerator = Accelerator(kwargs_handlers=[profile_kwargs])
+model = accelerator.prepare(model)
+
+with accelerator.profile() as prof:
+ for idx in range(8):
+ model(inputs)
+ prof.step()
+```
+
+
+
+
+## FLOPS
+
+Use formula to estimate the FLOPs (floating point operations) of specific operators (matrix multiplication and 2D convolution).
+
+To measure floating-point operations (FLOPS):
+
+
+
+
+```python
+with profile(
+ activities=[ProfilerActivity.CPU, ProfilerActivity.CUDA],
+ with_flops=True
+) as prof:
+ model(inputs)
+
+print(prof.key_averages().table(sort_by="flops", row_limit=10))
+```
+
+
+
+
+```python
+profile_kwargs = ProfileKwargs(
+ with_flops=True
+)
+accelerator = Accelerator(kwargs_handlers=[profile_kwargs])
+
+with accelerator.profile() as prof:
+ model(inputs)
+
+print(prof.key_averages().table(sort_by="flops", row_limit=10))
+```
+
+
+
+
+The resulting table output (omitting some columns):
+
+```
+------------------------------------------------------- ------------ ------------ ------------
+ Name Self CPU Self CUDA Total FLOPs
+------------------------------------------------------- ------------ ------------ ------------
+ aten::conv2d 197.000us 0.000us 18135613440.000
+ aten::addmm 103.000us 17.000us 5120000.000
+ aten::mul 29.000us 2.000us 30.000
+ aten::convolution 409.000us 0.000us --
+ aten::_convolution 253.000us 0.000us --
+ aten::cudnn_convolution 5.465ms 2.970ms --
+ cudaEventRecord 138.000us 0.000us --
+ cudaStreamIsCapturing 43.000us 0.000us --
+ cudaStreamGetPriority 40.000us 0.000us --
+ cudaDeviceGetStreamPriorityRange 10.000us 0.000us --
+------------------------------------------------------- ------------ ------------ ------------
+Self CPU time total: 21.938ms
+Self CUDA time total: 4.165ms
+```
+
+
+
+## Conclusion and Further Information
+
+PyTorch Profiler is a powerful tool for analyzing the performance of your models. By integrating it with Accelerate, you can easily profile your models and gain insights into their performance, helping you to optimize and improve them.
+
+For more detailed information, refer to the [PyTorch Profiler documentation](https://pytorch.org/docs/stable/profiler.html).
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/quantization.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/quantization.md
new file mode 100644
index 0000000000000000000000000000000000000000..e6046bc50ab7e7118ef68c9bbfc4ec7920865bfc
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/quantization.md
@@ -0,0 +1,138 @@
+
+
+# Model quantization
+
+## `bitsandbytes` Integration
+
+Accelerate brings `bitsandbytes` quantization to your model. You can now load any pytorch model in 8-bit or 4-bit with a few lines of code.
+
+If you want to use Transformers models with `bitsandbytes`, you should follow this [documentation](https://huggingface.co/docs/transformers/main_classes/quantization).
+
+To learn more about how the `bitsandbytes` quantization works, check out the blog posts on [8-bit quantization](https://huggingface.co/blog/hf-bitsandbytes-integration) and [4-bit quantization](https://huggingface.co/blog/4bit-transformers-bitsandbytes).
+
+### Pre-Requisites
+You will need to install the following requirements:
+
+- Install `bitsandbytes` library
+```bash
+pip install bitsandbytes
+```
+For non-cuda devices, you can refer to the bitsandbytes installation guide [here](https://huggingface.co/docs/bitsandbytes/main/en/installation#multi-backend).
+
+- Install latest `accelerate` from source
+```bash
+pip install git+https://github.com/huggingface/accelerate.git
+```
+- Install `minGPT` and `huggingface_hub` to run examples
+```bash
+git clone https://github.com/karpathy/minGPT.git
+pip install minGPT/
+pip install huggingface_hub
+```
+
+### How it works
+
+First, we need to initialize our model. To save memory, we can initialize an empty model using the context manager [`init_empty_weights`].
+
+Let's take the GPT2 model from minGPT library.
+```py
+from accelerate import init_empty_weights
+from mingpt.model import GPT
+
+model_config = GPT.get_default_config()
+model_config.model_type = 'gpt2-xl'
+model_config.vocab_size = 50257
+model_config.block_size = 1024
+
+with init_empty_weights():
+ empty_model = GPT(model_config)
+```
+
+Then, we need to get the path to the weights of your model. The path can be the state_dict file (e.g. "pytorch_model.bin") or a folder containing the sharded checkpoints.
+
+```py
+from huggingface_hub import snapshot_download
+weights_location = snapshot_download(repo_id="marcsun13/gpt2-xl-linear-sharded")
+```
+
+Finally, you need to set your quantization configuration with [`~utils.BnbQuantizationConfig`].
+
+Here's an example for 8-bit quantization:
+```py
+from accelerate.utils import BnbQuantizationConfig
+bnb_quantization_config = BnbQuantizationConfig(load_in_8bit=True, llm_int8_threshold = 6)
+```
+
+Here's an example for 4-bit quantization:
+```py
+from accelerate.utils import BnbQuantizationConfig
+bnb_quantization_config = BnbQuantizationConfig(load_in_4bit=True, bnb_4bit_compute_dtype=torch.bfloat16, bnb_4bit_use_double_quant=True, bnb_4bit_quant_type="nf4")
+```
+
+To quantize your empty model with the selected configuration, you need to use [`~utils.load_and_quantize_model`].
+
+```py
+from accelerate.utils import load_and_quantize_model
+quantized_model = load_and_quantize_model(empty_model, weights_location=weights_location, bnb_quantization_config=bnb_quantization_config)
+```
+
+### Saving and loading 8-bit model
+
+You can save your 8-bit model with accelerate using [`~Accelerator.save_model`].
+
+```py
+from accelerate import Accelerator
+accelerate = Accelerator()
+new_weights_location = "path/to/save_directory"
+accelerate.save_model(quantized_model, new_weights_location)
+
+quantized_model_from_saved = load_and_quantize_model(empty_model, weights_location=new_weights_location, bnb_quantization_config=bnb_quantization_config, device_map = "auto")
+```
+
+Note that 4-bit model serialization is currently not supported.
+
+### Offload modules to cpu and disk
+
+You can offload some modules to cpu/disk if you don't have enough space on the GPU to store the entire model on your GPUs.
+This uses big model inference under the hood. Check this [documentation](https://huggingface.co/docs/accelerate/usage_guides/big_modeling) for more details.
+
+For 8-bit quantization, the selected modules will be converted to 8-bit precision.
+
+For 4-bit quantization, the selected modules will be kept in `torch_dtype` that the user passed in `BnbQuantizationConfig`. We will add support to convert these offloaded modules in 4-bit when 4-bit serialization will be possible.
+
+ You just need to pass a custom `device_map` in order to offload modules on cpu/disk. The offload modules will be dispatched on the GPU when needed. Here's an example :
+
+```py
+device_map = {
+ "transformer.wte": 0,
+ "transformer.wpe": 0,
+ "transformer.drop": 0,
+ "transformer.h": "cpu",
+ "transformer.ln_f": "disk",
+ "lm_head": "disk",
+}
+```
+### Fine-tune a quantized model
+
+It is not possible to perform pure 8bit or 4bit training on these models. However, you can train these models by leveraging parameter efficient fine tuning methods (PEFT) and train for example adapters on top of them. Please have a look at [peft](https://github.com/huggingface/peft) library for more details.
+
+Currently, you can't add adapters on top of any quantized model. However, with the official support of adapters with Transformers models, you can fine-tune quantized models. If you want to finetune a Transformers model , follow this [documentation](https://huggingface.co/docs/transformers/main_classes/quantization) instead. Check out this [demo](https://colab.research.google.com/drive/1VoYNfYDKcKRQRor98Zbf2-9VQTtGJ24k?usp=sharing) on how to fine-tune a 4-bit Transformers model.
+
+Note that you don’t need to pass `device_map` when loading the model for training. It will automatically load your model on your GPU. Please note that `device_map=auto` should be used for inference only.
+
+### Example demo - running GPT2 1.5b on a Google Colab
+
+Check out the Google Colab [demo](https://colab.research.google.com/drive/1T1pOgewAWVpR9gKpaEWw4orOrzPFb3yM?usp=sharing) for running quantized models on a GPT2 model. The GPT2-1.5B model checkpoint is in FP32 which uses 6GB of memory. After quantization, it uses 1.6GB with 8-bit modules and 1.2GB with 4-bit modules.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/sagemaker.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/sagemaker.md
new file mode 100644
index 0000000000000000000000000000000000000000..700811404667aa5074686604bac83949b40ee5a1
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/sagemaker.md
@@ -0,0 +1,204 @@
+
+
+# Amazon SageMaker
+
+Hugging Face and Amazon introduced new [Hugging Face Deep Learning Containers (DLCs)](https://github.com/aws/deep-learning-containers/blob/master/available_images.md#huggingface-training-containers) to
+make it easier than ever to train Hugging Face Transformer models in [Amazon SageMaker](https://aws.amazon.com/sagemaker/).
+
+## Getting Started
+
+### Setup & Installation
+
+
+Before you can run your Accelerate scripts on Amazon SageMaker you need to sign up for an AWS account. If you do not
+have an AWS account yet learn more [here](https://docs.aws.amazon.com/sagemaker/latest/dg/gs-set-up.html).
+
+After you have your AWS Account you need to install the `sagemaker` sdk for Accelerate with:
+
+```bash
+pip install "accelerate[sagemaker]" --upgrade
+```
+
+Accelerate currently uses the DLCs, with `transformers`, `datasets` and `tokenizers` pre-installed. Accelerate is not in the DLC yet (will soon be added!) so to use it within Amazon SageMaker you need to create a
+`requirements.txt` in the same directory where your training script is located and add it as dependency:
+
+```
+accelerate
+```
+
+You should also add any other dependencies you have to this `requirements.txt`.
+
+
+### Configure Accelerate
+
+You can configure the launch configuration for Amazon SageMaker the same as you do for non SageMaker training jobs with
+the Accelerate CLI:
+
+```bash
+accelerate config
+# In which compute environment are you running? ([0] This machine, [1] AWS (Amazon SageMaker)): 1
+```
+
+Accelerate will go through a questionnaire about your Amazon SageMaker setup and create a config file you can edit.
+
+
+
+ Accelerate is not saving any of your credentials.
+
+
+
+### Prepare a Accelerate fine-tuning script
+
+The training script is very similar to a training script you might run outside of SageMaker, but to save your model
+after training you need to specify either `/opt/ml/model` or use `os.environ["SM_MODEL_DIR"]` as your save
+directory. After training, artifacts in this directory are uploaded to S3:
+
+
+```diff
+- torch.save('/opt/ml/model`)
++ accelerator.save('/opt/ml/model')
+```
+
+
+
+ SageMaker doesn’t support argparse actions. If you want to use, for example, boolean hyperparameters, you need to
+ specify type as bool in your script and provide an explicit True or False value for this hyperparameter. [[REF]](https://sagemaker.readthedocs.io/en/stable/frameworks/pytorch/using_pytorch.html#prepare-a-pytorch-training-script).
+
+
+
+### Launch Training
+
+You can launch your training with Accelerate CLI with:
+
+```
+accelerate launch path_to_script.py --args_to_the_script
+```
+
+This will launch your training script using your configuration. The only thing you have to do is provide all the
+arguments needed by your training script as named arguments.
+
+**Examples**
+
+
+
+ If you run one of the example scripts, don't forget to add `accelerator.save('/opt/ml/model')` to it.
+
+
+
+```bash
+accelerate launch ./examples/sagemaker_example.py
+```
+
+Outputs:
+
+```
+Configuring Amazon SageMaker environment
+Converting Arguments to Hyperparameters
+Creating Estimator
+2021-04-08 11:56:50 Starting - Starting the training job...
+2021-04-08 11:57:13 Starting - Launching requested ML instancesProfilerReport-1617883008: InProgress
+.........
+2021-04-08 11:58:54 Starting - Preparing the instances for training.........
+2021-04-08 12:00:24 Downloading - Downloading input data
+2021-04-08 12:00:24 Training - Downloading the training image..................
+2021-04-08 12:03:39 Training - Training image download completed. Training in progress..
+........
+epoch 0: {'accuracy': 0.7598039215686274, 'f1': 0.8178438661710037}
+epoch 1: {'accuracy': 0.8357843137254902, 'f1': 0.882249560632689}
+epoch 2: {'accuracy': 0.8406862745098039, 'f1': 0.8869565217391304}
+........
+2021-04-08 12:05:40 Uploading - Uploading generated training model
+2021-04-08 12:05:40 Completed - Training job completed
+Training seconds: 331
+Billable seconds: 331
+You can find your model data at: s3://your-bucket/accelerate-sagemaker-1-2021-04-08-11-56-47-108/output/model.tar.gz
+```
+
+## Advanced Features
+
+### Distributed Training: Data Parallelism
+
+Set up the accelerate config by running `accelerate config` and answer the SageMaker questions and set it up.
+To use SageMaker DDP, select it when asked
+`What is the distributed mode? ([0] No distributed training, [1] data parallelism):`.
+Example config below:
+```yaml
+base_job_name: accelerate-sagemaker-1
+compute_environment: AMAZON_SAGEMAKER
+distributed_type: DATA_PARALLEL
+ec2_instance_type: ml.p3.16xlarge
+iam_role_name: xxxxx
+image_uri: null
+mixed_precision: fp16
+num_machines: 1
+profile: xxxxx
+py_version: py10
+pytorch_version: 2.5.0
+region: us-east-1
+transformers_version: 4.17.0
+use_cpu: false
+```
+
+### Distributed Training: Model Parallelism
+
+*currently in development, will be supported soon.*
+
+### Python packages and dependencies
+
+Accelerate currently uses the DLCs, with `transformers`, `datasets` and `tokenizers` pre-installed. If you
+want to use different/other Python packages you can do this by adding them to the `requirements.txt`. These packages
+will be installed before your training script is started.
+
+### Local Training: SageMaker Local mode
+
+The local mode in the SageMaker SDK allows you to run your training script locally inside the HuggingFace DLC (Deep Learning container)
+or using your custom container image. This is useful for debugging and testing your training script inside the final container environment.
+Local mode uses Docker compose (*Note: Docker Compose V2 is not supported yet*). The SDK will handle the authentication against ECR
+to pull the DLC to your local environment. You can emulate CPU (single and multi-instance) and GPU (single instance) SageMaker training jobs.
+
+To use local mode, you need to set your `ec2_instance_type` to `local`.
+
+```yaml
+ec2_instance_type: local
+```
+
+### Advanced configuration
+
+The configuration allows you to override parameters for the [Estimator](https://sagemaker.readthedocs.io/en/stable/api/training/estimators.html).
+These settings have to be applied in the config file and are not part of `accelerate config`. You can control many additional aspects of the training job, e.g. use Spot instances, enable network isolation and many more.
+
+```yaml
+additional_args:
+ # enable network isolation to restrict internet access for containers
+ enable_network_isolation: True
+```
+
+You can find all available configuration [here](https://sagemaker.readthedocs.io/en/stable/api/training/estimators.html).
+
+### Use Spot Instances
+
+You can use Spot Instances e.g. using (see [Advanced configuration](#advanced-configuration)):
+```yaml
+additional_args:
+ use_spot_instances: True
+ max_wait: 86400
+```
+
+*Note: Spot Instances are subject to be terminated and training to be continued from a checkpoint. This is not handled in Accelerate out of the box. Contact us if you would like this feature.*
+
+### Remote scripts: Use scripts located on Github
+
+*undecided if feature is needed. Contact us if you would like this feature.*
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/tracking.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/tracking.md
new file mode 100644
index 0000000000000000000000000000000000000000..11fa84e191aac0a45acb776b17333560b570a04e
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/tracking.md
@@ -0,0 +1,234 @@
+
+
+# Experiment trackers
+
+There are a large number of experiment tracking APIs available, however getting them all to work in a multi-processing environment can oftentimes be complex.
+Accelerate provides a general tracking API that can be used to log useful items during your script through [`Accelerator.log`]
+
+## Integrated Trackers
+
+Currently `Accelerate` supports eight trackers out-of-the-box:
+
+- TensorBoard
+- WandB
+- Trackio
+- CometML
+- Aim
+- MLFlow
+- ClearML
+- DVCLive
+
+To use any of them, pass in the selected type(s) to the `log_with` parameter in [`Accelerate`]:
+```python
+from accelerate import Accelerator
+from accelerate.utils import LoggerType
+
+accelerator = Accelerator(log_with="all") # For all available trackers in the environment
+accelerator = Accelerator(log_with="wandb")
+accelerator = Accelerator(log_with=["wandb", LoggerType.TENSORBOARD])
+```
+
+At the start of your experiment [`Accelerator.init_trackers`] should be used to setup your project, and potentially add any experiment hyperparameters to be logged:
+```python
+hps = {"num_iterations": 5, "learning_rate": 1e-2}
+accelerator.init_trackers("my_project", config=hps)
+```
+
+When you are ready to log any data, [`Accelerator.log`] should be used.
+A `step` can also be passed in to correlate the data with a particular step in the training loop.
+```python
+accelerator.log({"train_loss": 1.12, "valid_loss": 0.8}, step=1)
+```
+
+Once you've finished training, make sure to run [`Accelerator.end_training`] so that all the trackers can run their finish functionalities if they have any.
+```python
+accelerator.end_training()
+```
+
+
+A full example is below:
+```python
+from accelerate import Accelerator
+
+accelerator = Accelerator(log_with="all")
+config = {
+ "num_iterations": 5,
+ "learning_rate": 1e-2,
+ "loss_function": str(my_loss_function),
+}
+
+accelerator.init_trackers("example_project", config=config)
+
+my_model, my_optimizer, my_training_dataloader = accelerator.prepare(my_model, my_optimizer, my_training_dataloader)
+device = accelerator.device
+my_model.to(device)
+
+for iteration in range(config["num_iterations"]):
+ for step, batch in enumerate(my_training_dataloader):
+ my_optimizer.zero_grad()
+ inputs, targets = batch
+ inputs = inputs.to(device)
+ targets = targets.to(device)
+ outputs = my_model(inputs)
+ loss = my_loss_function(outputs, targets)
+ accelerator.backward(loss)
+ my_optimizer.step()
+ accelerator.log({"training_loss": loss}, step=step)
+accelerator.end_training()
+```
+
+If a tracker requires a directory to save data to, such as `TensorBoard`, then pass the directory path to `project_dir`. The `project_dir` parameter is useful
+when there are other configurations to be combined with in the [`~utils.ProjectConfiguration`] data class. For example, you can save the TensorBoard data to `project_dir` and everything else can be logged in the `logging_dir` parameter of [`~utils.ProjectConfiguration`:
+
+```python
+accelerator = Accelerator(log_with="tensorboard", project_dir=".")
+
+# use with ProjectConfiguration
+config = ProjectConfiguration(project_dir=".", logging_dir="another/directory")
+accelerator = Accelerator(log_with="tensorboard", project_config=config)
+```
+
+## Implementing Custom Trackers
+
+To implement a new tracker to be used in `Accelerator`, a new one can be made through implementing the [`GeneralTracker`] class.
+Every tracker must implement three functions and have three properties:
+ - `__init__`:
+ - Should store a `run_name` and initialize the tracker API of the integrated library.
+ - If a tracker stores their data locally (such as TensorBoard), a `logging_dir` parameter can be added.
+ - `store_init_configuration`:
+ - Should take in a `values` dictionary and store them as a one-time experiment configuration
+ - `log`:
+ - Should take in a `values` dictionary and a `step`, and should log them to the run
+
+ - `name` (`str`):
+ - A unique string name for the tracker, such as `"wandb"` for the wandb tracker.
+ - This will be used for interacting with this tracker specifically
+ - `requires_logging_directory` (`bool`):
+ - Whether a `logging_dir` is needed for this particular tracker and if it uses one.
+ - `tracker`:
+ - This should be implemented as a `@property` function
+ - Should return the internal tracking mechanism the library uses, such as the `run` object for `wandb`.
+
+Each method should also utilize the [`state.PartialState`] class if the logger should only be executed on the main process for instance.
+
+A brief example can be seen below with an integration with Weights and Biases, containing only the relevant information and logging just on
+the main process:
+```python
+from accelerate.tracking import GeneralTracker, on_main_process
+from typing import Optional
+
+import wandb
+
+
+class MyCustomTracker(GeneralTracker):
+ name = "wandb"
+ requires_logging_directory = False
+
+ @on_main_process
+ def __init__(self, run_name: str):
+ self.run_name = run_name
+ run = wandb.init(self.run_name)
+
+ @property
+ def tracker(self):
+ return self.run.run
+
+ @on_main_process
+ def store_init_configuration(self, values: dict):
+ wandb.config(values)
+
+ @on_main_process
+ def log(self, values: dict, step: Optional[int] = None):
+ wandb.log(values, step=step)
+```
+
+When you are ready to build your `Accelerator` object, pass in an **instance** of your tracker to [`Accelerator.log_with`] to have it automatically
+be used with the API:
+
+```python
+tracker = MyCustomTracker("some_run_name")
+accelerator = Accelerator(log_with=tracker)
+```
+
+These also can be mixed with existing trackers, including with `"all"`:
+
+```python
+tracker = MyCustomTracker("some_run_name")
+accelerator = Accelerator(log_with=[tracker, "all"])
+```
+
+## Accessing the internal tracker
+
+If some custom interactions with a tracker might be wanted directly, you can quickly access one using the
+[`Accelerator.get_tracker`] method. Just pass in the string corresponding to a tracker's `.name` attribute
+and it will return that tracker on the main process.
+
+This example shows doing so with wandb:
+
+```python
+wandb_tracker = accelerator.get_tracker("wandb")
+```
+
+From there you can interact with `wandb`'s `run` object like normal:
+
+```python
+wandb_tracker.log_artifact(some_artifact_to_log)
+```
+
+
+ Trackers built in Accelerate will automatically execute on the correct process,
+ so if a tracker is only meant to be ran on the main process it will do so
+ automatically.
+
+
+If you want to truly remove Accelerate's wrapping entirely, you can
+achieve the same outcome with:
+
+```python
+wandb_tracker = accelerator.get_tracker("wandb", unwrap=True)
+if accelerator.is_main_process:
+ wandb_tracker.log_artifact(some_artifact_to_log)
+```
+
+
+## When a wrapper cannot work
+
+If a library has an API that does not follow a strict `.log` with an overall dictionary such as Neptune.AI, logging can be done manually under an `if accelerator.is_main_process` statement:
+```diff
+ from accelerate import Accelerator
++ import neptune
+
+ accelerator = Accelerator()
++ run = neptune.init_run(...)
+
+ my_model, my_optimizer, my_training_dataloader = accelerate.prepare(my_model, my_optimizer, my_training_dataloader)
+ device = accelerator.device
+ my_model.to(device)
+
+ for iteration in config["num_iterations"]:
+ for batch in my_training_dataloader:
+ my_optimizer.zero_grad()
+ inputs, targets = batch
+ inputs = inputs.to(device)
+ targets = targets.to(device)
+ outputs = my_model(inputs)
+ loss = my_loss_function(outputs, targets)
+ total_loss += loss
+ accelerator.backward(loss)
+ my_optimizer.step()
++ if accelerator.is_main_process:
++ run["logs/training/batch/loss"].log(loss)
+```
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/training_zoo.md b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/training_zoo.md
new file mode 100644
index 0000000000000000000000000000000000000000..1892f195d7e619244ea1a9b6602f31d686e1af25
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/docs/source/usage_guides/training_zoo.md
@@ -0,0 +1,180 @@
+
+
+# Example Zoo
+
+Below contains a non-exhaustive list of tutorials and scripts showcasing Accelerate.
+
+## Official Accelerate Examples:
+
+### Basic Examples
+
+These examples showcase the base features of Accelerate and are a great starting point
+
+- [Barebones NLP example](https://github.com/huggingface/accelerate/blob/main/examples/nlp_example.py)
+- [Barebones distributed NLP example in a Jupyter Notebook](https://github.com/huggingface/notebooks/blob/main/examples/accelerate_examples/simple_nlp_example.ipynb)
+- [Barebones computer vision example](https://github.com/huggingface/accelerate/blob/main/examples/cv_example.py)
+- [Barebones distributed computer vision example in a Jupyter Notebook](https://github.com/huggingface/notebooks/blob/main/examples/accelerate_examples/simple_cv_example.ipynb)
+- [Using Accelerate in Kaggle](https://www.kaggle.com/code/muellerzr/multi-gpu-and-accelerate)
+
+### Feature Specific Examples
+
+These examples showcase specific features that the Accelerate framework offers
+
+- [Automatic memory-aware gradient accumulation](https://github.com/huggingface/accelerate/blob/main/examples/by_feature/automatic_gradient_accumulation.py)
+- [Checkpointing states](https://github.com/huggingface/accelerate/blob/main/examples/by_feature/checkpointing.py)
+- [Cross validation](https://github.com/huggingface/accelerate/blob/main/examples/by_feature/cross_validation.py)
+- [DeepSpeed](https://github.com/huggingface/accelerate/blob/main/examples/by_feature/deepspeed_with_config_support.py)
+- [Fully Sharded Data Parallelism](https://github.com/huggingface/accelerate/blob/main/examples/by_feature/fsdp_with_peak_mem_tracking.py)
+- [Gradient accumulation](https://github.com/huggingface/accelerate/blob/main/examples/by_feature/gradient_accumulation.py)
+- [Memory-aware batch size finder](https://github.com/huggingface/accelerate/blob/main/examples/by_feature/memory.py)
+- [Metric Computation](https://github.com/huggingface/accelerate/blob/main/examples/by_feature/multi_process_metrics.py)
+- [Using Trackers](https://github.com/huggingface/accelerate/blob/main/examples/by_feature/tracking.py)
+- [Using Megatron-LM](https://github.com/huggingface/accelerate/blob/main/examples/by_feature/megatron_lm_gpt_pretraining.py)
+
+### Full Examples
+
+These examples showcase every feature in Accelerate at once that was shown in "Feature Specific Examples"
+
+- [Complete NLP example](https://github.com/huggingface/accelerate/blob/main/examples/complete_nlp_example.py)
+- [Complete computer vision example](https://github.com/huggingface/accelerate/blob/main/examples/complete_cv_example.py)
+- [Very complete and extensible vision example showcasing SLURM, hydra, and a very extensible usage of the framework](https://github.com/yuvalkirstain/PickScore)
+- [Causal language model fine-tuning example](https://github.com/huggingface/transformers/blob/main/examples/pytorch/language-modeling/run_clm_no_trainer.py)
+- [Masked language model fine-tuning example](https://github.com/huggingface/transformers/blob/main/examples/pytorch/language-modeling/run_mlm_no_trainer.py)
+- [Speech pretraining example](https://github.com/huggingface/transformers/blob/main/examples/pytorch/speech-pretraining/run_wav2vec2_pretraining_no_trainer.py)
+- [Translation fine-tuning example](https://github.com/huggingface/transformers/blob/main/examples/pytorch/translation/run_translation_no_trainer.py)
+- [Text classification fine-tuning example](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-classification/run_glue_no_trainer.py)
+- [Semantic segmentation fine-tuning example](https://github.com/huggingface/transformers/blob/main/examples/pytorch/semantic-segmentation/run_semantic_segmentation_no_trainer.py)
+- [Question answering fine-tuning example](https://github.com/huggingface/transformers/blob/main/examples/pytorch/question-answering/run_qa_no_trainer.py)
+- [Beam search question answering fine-tuning example](https://github.com/huggingface/transformers/blob/main/examples/pytorch/question-answering/run_qa_beam_search_no_trainer.py)
+- [Multiple choice question answering fine-tuning example](https://github.com/huggingface/transformers/blob/main/examples/pytorch/multiple-choice/run_swag_no_trainer.py)
+- [Named entity recognition fine-tuning example](https://github.com/huggingface/transformers/blob/main/examples/pytorch/token-classification/run_ner_no_trainer.py)
+- [Image classification fine-tuning example](https://github.com/huggingface/transformers/blob/main/examples/pytorch/image-classification/run_image_classification_no_trainer.py)
+- [Summarization fine-tuning example](https://github.com/huggingface/transformers/blob/main/examples/pytorch/summarization/run_summarization_no_trainer.py)
+- [End-to-end examples on how to use AWS SageMaker integration of Accelerate](https://github.com/huggingface/notebooks/blob/main/sagemaker/22_accelerate_sagemaker_examples/README.md)
+- [Megatron-LM examples for various NLp tasks](https://github.com/pacman100/accelerate-megatron-test)
+
+## Integration Examples
+
+These are tutorials from libraries that integrate with Accelerate:
+
+> Don't find your integration here? Make a PR to include it!
+
+### Amphion
+- [Training Text-to-Speech Models with Amphion](https://github.com/open-mmlab/Amphion/blob/main/egs/tts/README.md)
+- [Training Singing Voice Conversion Models with Amphion](https://github.com/open-mmlab/Amphion/blob/main/egs/svc/README.md)
+- [Training Vocoders with Amphion](https://github.com/open-mmlab/Amphion/blob/main/egs/vocoder/README.md)
+
+### Catalyst
+
+- [Distributed training tutorial with Catalyst](https://catalyst-team.github.io/catalyst/tutorials/ddp.html)
+
+### DALLE2-pytorch
+
+- [Fine-tuning DALLE2](https://github.com/lucidrains/DALLE2-pytorch#usage)
+
+### Diffusers
+
+- [Performing textual inversion with diffusers](https://github.com/huggingface/diffusers/tree/main/examples/textual_inversion)
+- [Training DreamBooth with diffusers](https://github.com/huggingface/diffusers/tree/main/examples/dreambooth)
+
+### fastai
+
+- [Distributed training from Jupyter Notebooks with fastai](https://docs.fast.ai/tutorial.distributed.html)
+- [Basic distributed training examples with fastai](https://docs.fast.ai/examples/distributed_app_examples.html)
+
+### GradsFlow
+
+- [Auto Image Classification with GradsFlow](https://docs.gradsflow.com/en/latest/examples/nbs/01-ImageClassification/)
+
+### imagen-pytorch
+
+- [Fine-tuning Imagen](https://github.com/lucidrains/imagen-pytorch#usage)
+
+### Kornia
+
+- [Fine-tuning vision models with Kornia's Trainer](https://kornia.readthedocs.io/en/latest/get-started/training.html)
+
+### PyTorch Accelerated
+
+- [Quickstart distributed training tutorial with PyTorch Accelerated](https://pytorch-accelerated.readthedocs.io/en/latest/quickstart.html)
+
+### PyTorch3D
+
+- [Perform Deep Learning with 3D data](https://pytorch3d.org/tutorials/)
+
+### Stable-Dreamfusion
+
+- [Training with Stable-Dreamfusion to convert text to a 3D model](https://colab.research.google.com/drive/1MXT3yfOFvO0ooKEfiUUvTKwUkrrlCHpF?usp=sharing)
+
+### Tez
+
+- [Leaf disease detection with Tez and Accelerate](https://www.kaggle.com/code/abhishek/tez-faster-and-easier-training-for-leaf-detection/notebook)
+
+### trlx
+
+- [How to implement a sentiment learning task with trlx](https://github.com/CarperAI/trlx#example-how-to-add-a-task)
+
+### Comfy-UI
+
+- [Enabling using large Stable Diffusion Models in low-vram settings using Accelerate](https://github.com/comfyanonymous/ComfyUI/blob/master/comfy/model_management.py#L291-L296)
+
+
+## In Science
+
+Below contains a non-exhaustive list of papers utilizing Accelerate.
+
+> Don't find your paper here? Make a PR to include it!
+
+* Yuval Kirstain, Adam Polyak, Uriel Singer, Shahbuland Matiana, Joe Penna, Omer Levy: “Pick-a-Pic: An Open Dataset of User Preferences for Text-to-Image Generation”, 2023; [arXiv:2305.01569](http://huggingface.co/papers/2305.01569).
+* Lei Wang, Wanyu Xu, Yihuai Lan, Zhiqiang Hu, Yunshi Lan, Roy Ka-Wei Lee, Ee-Peng Lim: “Plan-and-Solve Prompting: Improving Zero-Shot Chain-of-Thought Reasoning by Large Language Models”, 2023; [arXiv:2305.04091](http://huggingface.co/papers/2305.04091).
+* Arthur Câmara, Claudia Hauff: “Moving Stuff Around: A study on efficiency of moving documents into memory for Neural IR models”, 2022; [arXiv:2205.08343](http://huggingface.co/papers/2205.08343).
+* Ying Sheng, Lianmin Zheng, Binhang Yuan, Zhuohan Li, Max Ryabinin, Daniel Y. Fu, Zhiqiang Xie, Beidi Chen, Clark Barrett, Joseph E. Gonzalez, Percy Liang, Christopher Ré, Ion Stoica, Ce Zhang: “High-throughput Generative Inference of Large Language Models with a Single GPU”, 2023; [arXiv:2303.06865](http://huggingface.co/papers/2303.06865).
+* Peter Melchior, Yan Liang, ChangHoon Hahn, Andy Goulding: “Autoencoding Galaxy Spectra I: Architecture”, 2022; [arXiv:2211.07890](http://huggingface.co/papers/2211.07890).
+* Jiaao Chen, Aston Zhang, Mu Li, Alex Smola, Diyi Yang: “A Cheaper and Better Diffusion Language Model with Soft-Masked Noise”, 2023; [arXiv:2304.04746](http://huggingface.co/papers/2304.04746).
+* Ayaan Haque, Matthew Tancik, Alexei A. Efros, Aleksander Holynski, Angjoo Kanazawa: “Instruct-NeRF2NeRF: Editing 3D Scenes with Instructions”, 2023; [arXiv:2303.12789](http://huggingface.co/papers/2303.12789).
+* Luke Melas-Kyriazi, Christian Rupprecht, Iro Laina, Andrea Vedaldi: “RealFusion: 360° Reconstruction of Any Object from a Single Image”, 2023; [arXiv:2302.10663](http://huggingface.co/papers/2302.10663).
+* Xiaoshi Wu, Keqiang Sun, Feng Zhu, Rui Zhao, Hongsheng Li: “Better Aligning Text-to-Image Models with Human Preference”, 2023; [arXiv:2303.14420](http://huggingface.co/papers/2303.14420).
+* Yongliang Shen, Kaitao Song, Xu Tan, Dongsheng Li, Weiming Lu, Yueting Zhuang: “HuggingGPT: Solving AI Tasks with ChatGPT and its Friends in HuggingFace”, 2023; [arXiv:2303.17580](http://huggingface.co/papers/2303.17580).
+* Yue Yang, Wenlin Yao, Hongming Zhang, Xiaoyang Wang, Dong Yu, Jianshu Chen: “Z-LaVI: Zero-Shot Language Solver Fueled by Visual Imagination”, 2022; [arXiv:2210.12261](http://huggingface.co/papers/2210.12261).
+* Sheng-Yen Chou, Pin-Yu Chen, Tsung-Yi Ho: “How to Backdoor Diffusion Models?”, 2022; [arXiv:2212.05400](http://huggingface.co/papers/2212.05400).
+* Junyoung Seo, Wooseok Jang, Min-Seop Kwak, Jaehoon Ko, Hyeonsu Kim, Junho Kim, Jin-Hwa Kim, Jiyoung Lee, Seungryong Kim: “Let 2D Diffusion Model Know 3D-Consistency for Robust Text-to-3D Generation”, 2023; [arXiv:2303.07937](http://huggingface.co/papers/2303.07937).
+* Or Patashnik, Daniel Garibi, Idan Azuri, Hadar Averbuch-Elor, Daniel Cohen-Or: “Localizing Object-level Shape Variations with Text-to-Image Diffusion Models”, 2023; [arXiv:2303.11306](http://huggingface.co/papers/2303.11306).
+* Dídac Surís, Sachit Menon, Carl Vondrick: “ViperGPT: Visual Inference via Python Execution for Reasoning”, 2023; [arXiv:2303.08128](http://huggingface.co/papers/2303.08128).
+* Chenyang Qi, Xiaodong Cun, Yong Zhang, Chenyang Lei, Xintao Wang, Ying Shan, Qifeng Chen: “FateZero: Fusing Attentions for Zero-shot Text-based Video Editing”, 2023; [arXiv:2303.09535](http://huggingface.co/papers/2303.09535).
+* Sean Welleck, Jiacheng Liu, Ximing Lu, Hannaneh Hajishirzi, Yejin Choi: “NaturalProver: Grounded Mathematical Proof Generation with Language Models”, 2022; [arXiv:2205.12910](http://huggingface.co/papers/2205.12910).
+* Elad Richardson, Gal Metzer, Yuval Alaluf, Raja Giryes, Daniel Cohen-Or: “TEXTure: Text-Guided Texturing of 3D Shapes”, 2023; [arXiv:2302.01721](http://huggingface.co/papers/2302.01721).
+* Puijin Cheng, Li Lin, Yijin Huang, Huaqing He, Wenhan Luo, Xiaoying Tang: “Learning Enhancement From Degradation: A Diffusion Model For Fundus Image Enhancement”, 2023; [arXiv:2303.04603](http://huggingface.co/papers/2303.04603).
+* Shun Shao, Yftah Ziser, Shay Cohen: “Erasure of Unaligned Attributes from Neural Representations”, 2023; [arXiv:2302.02997](http://huggingface.co/papers/2302.02997).
+* Seonghyeon Ye, Hyeonbin Hwang, Sohee Yang, Hyeongu Yun, Yireun Kim, Minjoon Seo: “In-Context Instruction Learning”, 2023; [arXiv:2302.14691](http://huggingface.co/papers/2302.14691).
+* Shikun Liu, Linxi Fan, Edward Johns, Zhiding Yu, Chaowei Xiao, Anima Anandkumar: “Prismer: A Vision-Language Model with An Ensemble of Experts”, 2023; [arXiv:2303.02506](http://huggingface.co/papers/2303.02506).
+* Haoyu Chen, Zhihua Wang, Yang Yang, Qilin Sun, Kede Ma: “Learning a Deep Color Difference Metric for Photographic Images”, 2023; [arXiv:2303.14964](http://huggingface.co/papers/2303.14964).
+* Van-Hoang Le, Hongyu Zhang: “Log Parsing with Prompt-based Few-shot Learning”, 2023; [arXiv:2302.07435](http://huggingface.co/papers/2302.07435).
+* Keito Kudo, Yoichi Aoki, Tatsuki Kuribayashi, Ana Brassard, Masashi Yoshikawa, Keisuke Sakaguchi, Kentaro Inui: “Do Deep Neural Networks Capture Compositionality in Arithmetic Reasoning?”, 2023; [arXiv:2302.07866](http://huggingface.co/papers/2302.07866).
+* Ruoyao Wang, Peter Jansen, Marc-Alexandre Côté, Prithviraj Ammanabrolu: “Behavior Cloned Transformers are Neurosymbolic Reasoners”, 2022; [arXiv:2210.07382](http://huggingface.co/papers/2210.07382).
+* Martin Wessel, Tomáš Horych, Terry Ruas, Akiko Aizawa, Bela Gipp, Timo Spinde: “Introducing MBIB -- the first Media Bias Identification Benchmark Task and Dataset Collection”, 2023; [arXiv:2304.13148](http://huggingface.co/papers/2304.13148). DOI: [https://dx.doi.org/10.1145/3539618.3591882 10.1145/3539618.3591882].
+* Hila Chefer, Yuval Alaluf, Yael Vinker, Lior Wolf, Daniel Cohen-Or: “Attend-and-Excite: Attention-Based Semantic Guidance for Text-to-Image Diffusion Models”, 2023; [arXiv:2301.13826](http://huggingface.co/papers/2301.13826).
+* Marcio Fonseca, Yftah Ziser, Shay B. Cohen: “Factorizing Content and Budget Decisions in Abstractive Summarization of Long Documents”, 2022; [arXiv:2205.12486](http://huggingface.co/papers/2205.12486).
+* Elad Richardson, Gal Metzer, Yuval Alaluf, Raja Giryes, Daniel Cohen-Or: “TEXTure: Text-Guided Texturing of 3D Shapes”, 2023; [arXiv:2302.01721](http://huggingface.co/papers/2302.01721).
+* Tianxing He, Jingyu Zhang, Tianle Wang, Sachin Kumar, Kyunghyun Cho, James Glass, Yulia Tsvetkov: “On the Blind Spots of Model-Based Evaluation Metrics for Text Generation”, 2022; [arXiv:2212.10020](http://huggingface.co/papers/2212.10020).
+* Ori Ram, Yoav Levine, Itay Dalmedigos, Dor Muhlgay, Amnon Shashua, Kevin Leyton-Brown, Yoav Shoham: “In-Context Retrieval-Augmented Language Models”, 2023; [arXiv:2302.00083](http://huggingface.co/papers/2302.00083).
+* Dacheng Li, Rulin Shao, Hongyi Wang, Han Guo, Eric P. Xing, Hao Zhang: “MPCFormer: fast, performant and private Transformer inference with MPC”, 2022; [arXiv:2211.01452](http://huggingface.co/papers/2211.01452).
+* Baolin Peng, Michel Galley, Pengcheng He, Chris Brockett, Lars Liden, Elnaz Nouri, Zhou Yu, Bill Dolan, Jianfeng Gao: “GODEL: Large-Scale Pre-Training for Goal-Directed Dialog”, 2022; [arXiv:2206.11309](http://huggingface.co/papers/2206.11309).
+* Egil Rønningstad, Erik Velldal, Lilja Øvrelid: “Entity-Level Sentiment Analysis (ELSA): An exploratory task survey”, 2023, Proceedings of the 29th International Conference on Computational Linguistics, 2022, pages 6773-6783; [arXiv:2304.14241](http://huggingface.co/papers/2304.14241).
+* Charlie Snell, Ilya Kostrikov, Yi Su, Mengjiao Yang, Sergey Levine: “Offline RL for Natural Language Generation with Implicit Language Q Learning”, 2022; [arXiv:2206.11871](http://huggingface.co/papers/2206.11871).
+* Zhiruo Wang, Shuyan Zhou, Daniel Fried, Graham Neubig: “Execution-Based Evaluation for Open-Domain Code Generation”, 2022; [arXiv:2212.10481](http://huggingface.co/papers/2212.10481).
+* Minh-Long Luu, Zeyi Huang, Eric P. Xing, Yong Jae Lee, Haohan Wang: “Expeditious Saliency-guided Mix-up through Random Gradient Thresholding”, 2022; [arXiv:2212.04875](http://huggingface.co/papers/2212.04875).
+* Jun Hao Liew, Hanshu Yan, Daquan Zhou, Jiashi Feng: “MagicMix: Semantic Mixing with Diffusion Models”, 2022; [arXiv:2210.16056](http://huggingface.co/papers/2210.16056).
+* Yaqing Wang, Subhabrata Mukherjee, Xiaodong Liu, Jing Gao, Ahmed Hassan Awadallah, Jianfeng Gao: “LiST: Lite Prompted Self-training Makes Parameter-Efficient Few-shot Learners”, 2021; [arXiv:2110.06274](http://huggingface.co/papers/2110.06274).
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/README.md b/tasks/tasksmith-3d762a2acfee/tests/source/examples/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..25992affd2e97058883efb2a9897cedc84dcff92
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/README.md
@@ -0,0 +1,282 @@
+
+
+# In this folder we showcase various full examples using 🤗 Accelerate
+
+## Simple NLP example
+
+The [nlp_example.py](./nlp_example.py) script is a simple example to train a Bert model on a classification task ([GLUE's MRPC](https://www.microsoft.com/en-us/download/details.aspx?id=52398)).
+
+Prior to running it you should install 🤗 Dataset and 🤗 Transformers:
+
+```bash
+pip install datasets evaluate transformers
+```
+
+The same script can be run in any of the following configurations:
+- single CPU or single GPU
+- multi CPUs
+- multi GPUs (using PyTorch distributed mode)
+- (multi) TPUs
+- fp16 (mixed-precision) or fp32 (normal precision)
+
+To run it in each of these various modes, use the following commands:
+- single CPU:
+ * from a server without GPU
+ ```bash
+ python ./nlp_example.py
+ ```
+ * from any server by passing `cpu=True` to the `Accelerator`.
+ ```bash
+ python ./nlp_example.py --cpu
+ ```
+ * from any server with Accelerate launcher
+ ```bash
+ accelerate launch --cpu ./nlp_example.py
+ ```
+- single GPU:
+ ```bash
+ python ./nlp_example.py # from a server with a GPU
+ ```
+- with fp16 (mixed-precision)
+ * from any server by passing `mixed_precison=fp16` to the `Accelerator`.
+ ```bash
+ python ./nlp_example.py --mixed_precision fp16
+ ```
+ * from any server with Accelerate launcher
+ ```bash
+ accelerate launch --mixed_precision fp16 ./nlp_example.py
+- multi CPUs (requires Open MPI, Intel MPI, or MVAPICH)
+ * With Accelerate config and launcher, execute the following from node 0:
+ ```bash
+ accelerate config # Select to have accelerate launch mpirun
+ accelerate launch ./nlp_example.py # This will run the script on each server
+ ```
+ * With Intel MPI:
+ ```bash
+ export CCL_WORKER_COUNT=1
+ export MASTER_ADDR=xxx.xxx.xxx.xxx #node0 ip
+ mpirun -f hostfile -n 16 -ppn 4 python ./nlp_example.py
+ ```
+- multi GPUs (using PyTorch distributed mode)
+ * With Accelerate config and launcher
+ ```bash
+ accelerate config # This will create a config file on your server
+ accelerate launch ./nlp_example.py # This will run the script on your server
+ ```
+ * With traditional PyTorch launcher (`python -m torch.distributed.run` can be used instead of `torchrun`)
+ ```bash
+ torchrun --nproc_per_node 2 ./nlp_example.py
+ ```
+- multi GPUs, multi node (several machines, using PyTorch distributed mode)
+ * With Accelerate config and launcher, on each machine:
+ ```bash
+ accelerate config # This will create a config file on each server
+ accelerate launch ./nlp_example.py # This will run the script on each server
+ ```
+ * With PyTorch launcher only (`python -m torch.distributed.run` can be used instead of `torchrun`). Run this command on each node:
+ ```bash
+ torchrun \ # python -m torch.distributed.run
+ --nproc_per_node 2 \
+ --nnodes 2 \
+ --rdzv_id 2299 \ # A unique job id
+ --rdzv_backend c10d \
+ --rdzv_endpoint master_node_ip_address:29500 \
+ ./nlp_example.py
+ ```
+- (multi) TPUs
+ * With Accelerate config and launcher
+ ```bash
+ accelerate config # This will create a config file on your TPU server
+ accelerate launch ./nlp_example.py # This will run the script on each server
+ ```
+ * In PyTorch:
+ Add an `xmp.spawn` line in your script as you usually do.
+
+
+## Simple vision example
+
+The [cv_example.py](./cv_example.py) script is a simple example to fine-tune a ResNet-50 on a classification task ([Ofxord-IIT Pet Dataset](https://www.robots.ox.ac.uk/~vgg/data/pets/)).
+
+The same script can be run in any of the following configurations:
+- single CPU or single GPU
+- multi CPUs
+- multi GPUs (using PyTorch distributed mode)
+- (multi) TPUs
+- fp16 (mixed-precision) or fp32 (normal precision)
+
+Prior to running it you should install timm and torchvision:
+
+```bash
+pip install timm torchvision
+```
+
+and you should download the data with the following commands:
+
+```bash
+wget https://www.robots.ox.ac.uk/~vgg/data/pets/data/images.tar.gz
+tar -xzf images.tar.gz
+```
+
+To run it in each of these various modes, use the following commands:
+- single CPU:
+ * from a server without GPU
+ ```bash
+ python ./cv_example.py --data_dir path_to_data
+ ```
+ * from any server by passing `cpu=True` to the `Accelerator`.
+ ```bash
+ python ./cv_example.py --data_dir path_to_data --cpu
+ ```
+ * from any server with Accelerate launcher
+ ```bash
+ accelerate launch --cpu ./cv_example.py --data_dir path_to_data
+ ```
+- single GPU:
+ ```bash
+ python ./cv_example.py # from a server with a GPU
+ ```
+- with fp16 (mixed-precision)
+ * from any server by passing `mixed_precison=fp16` to the `Accelerator`.
+ ```bash
+ python ./cv_example.py --data_dir path_to_data --mixed_precison fp16
+ ```
+ * from any server with Accelerate launcher
+ ```bash
+ accelerate launch --mixed_precison fp16 ./cv_example.py --data_dir path_to_data
+- multi CPUs (requires Open MPI, Intel MPI, or MVAPICH)
+ * With Accelerate config and launcher, run the following from node 0:
+ ```bash
+ accelerate config --config_file config.yaml # Select to have accelerate launch mpirun
+ accelerate launch ./cv_example.py --data_dir path_to_data # This will run the script on each server
+ ```
+ * With Intel MPI, execute mpirun from node 0:
+ ```bash
+ export CCL_WORKER_COUNT=1
+ export MASTER_ADDR=xxx.xxx.xxx.xxx #node0 ip
+ mpirun -f hostfile -n 16 -ppn 4 python ./cv_example.py --data_dir path_to_data
+ ```
+- multi GPUs (using PyTorch distributed mode)
+ * With Accelerate config and launcher
+ ```bash
+ accelerate config --config_file config.yaml # This will create a config file on your server to `config.yaml`
+ accelerate launch --config_file config.yaml ./cv_example.py --data_dir path_to_data # This will run the script on your server
+ ```
+ * With traditional PyTorch launcher (`python -m torch.distributed.run` can be used instead of `torchrun`)
+ ```bash
+ torchrun --nproc_per_node 2 ./cv_example.py --data_dir path_to_data
+ ```
+- multi GPUs, multi node (several machines, using PyTorch distributed mode)
+ * With Accelerate config and launcher, on each machine:
+ ```bash
+ accelerate config --config_file config.yaml # This will create a config file on your server to `config.yaml`
+ accelerate launch --config_file config.yaml ./cv_example.py --data_dir path_to_data # This will run the script on each server
+ ```
+ * With PyTorch launcher only (`python -m torch.distributed.run` can be used instead of `torchrun`). Run this command on each node:
+ ```bash
+ torchrun \ # python -m torch.distributed.run
+ --nproc_per_node 2 \
+ --nnodes 2 \
+ --rdzv_id 2299 \ # A unique job id
+ --rdzv_backend c10d \
+ --rdzv_endpoint master_node_ip_address:29500 \
+ ./cv_example.py --data_dir path_to_data
+ ```
+- (multi) TPUs
+ * With Accelerate config and launcher
+ ```bash
+ accelerate config --config_file config.yaml # This will create a config file on your server to `config.yaml`
+ accelerate launch --config_file config.yaml ./cv_example.py --data_dir path_to_data # This will run the script on each server
+ ```
+ * In PyTorch:
+ Add an `xmp.spawn` line in your script as you usually do.
+
+### Simple vision example (GANs)
+
+- [huggan project](https://github.com/huggingface/community-events/tree/main/huggan)
+
+
+### Using AWS SageMaker integration
+- [Examples showcasing AWS SageMaker integration of 🤗 Accelerate.](https://github.com/pacman100/accelerate-aws-sagemaker)
+
+## Configuration zoo
+In [/config_yaml_templates](./config_yaml_templates/) we have a variety of *minimal* `config.yaml` templates and examples to help you learn
+how to create your own configuration files depending on the scenario.
+
+## SLURM Scripts
+In [/slurm/submit_multigpu.sh](./slurm/submit_multigpu.sh) and [/slurm/submit_multinode.sh](./slurm/submit_multinode.sh) we present two scripts for running the examples on a machine with [SLURM](https://slurm.schedmd.com/documentation.html) workload manager.
+
+In [/slurm/submit_multigpu.sh](./slurm/submit_multigpu.sh) the only parameter in the launcher that needs to be modified is `--num_processes`, which determines the number of GPUs we will use. In this case, using the environment variable `$SLURM_GPUS`, we indicate that we want to utilize all the GPUs available on the node we have requested.
+
+In [/slurm/submit_multinode.sh](./slurm/submit_multinode.sh) we must specify the number of nodes that will be part of the training (`--num_machines`), how many GPUs we will use in total (`--num_processes`), the [`backend`](https://pytorch.org/docs/stable/elastic/run.html#note-on-rendezvous-backend), `--main_process_ip` which will be the address the master node and the `--main_process_port`.
+
+In [/slurm/submit_multicpu.sh](./slurm/submit_multicpu.sh) we must specify the number of nodes that will be part of the training (`--num_machines`), how many CPU processes we will use in total (`--num_processes`), the [`backend`](https://pytorch.org/docs/stable/elastic/run.html#note-on-rendezvous-backend), `--main_process_ip` which will be the address the master node and the `--main_process_port`. `mpirun_hostfile` specifies to run the job using MPIRun.
+
+In both scripts, we run `activateEnvironment.sh` at the beginning. This script should contain the necessary instructions to initialize the environment for execution. Below, we show an example that loads the necessary libraries ([Environment modules](https://github.com/cea-hpc/modules)), activates the Python environment, and sets up various environment variables, most of them to run the scripts in offline mode in case we don't have internet connection from the cluster.
+
+```bash
+# activateEnvironment.sh
+module purge
+module load anaconda3/2020.02 cuda/10.2 cudnn/8.0.5 nccl/2.9.9 arrow/7.0.0 openmpi
+source activate /home/nct01/nct01328/pytorch_antoni_local
+
+export HF_HOME=/gpfs/projects/nct01/nct01328/
+export HF_LOCAL_HOME=/gpfs/projects/nct01/nct01328/HF_LOCAL
+export HF_DATASETS_OFFLINE=1
+export TRANSFORMERS_OFFLINE=1
+export PYTHONPATH=/home/nct01/nct01328/transformers-in-supercomputers:$PYTHONPATH
+export GPUS_PER_NODE=4
+```
+
+## Simple Multi-GPU Hardware Launcher (using an external platform)
+
+[multigpu_remote_launcher.py](./multigpu_remote_launcher.py) is a minimal script that demonstrates launching accelerate
+on multiple remote GPUs, and with automatic hardware environment and dependency setup for reproducibility. You can
+easily customize the training function used, training arguments, hyperparameters, and type of compute hardware, and then
+run the script to automatically launch multi GPU training on remote hardware.
+
+This script uses [Runhouse](https://github.com/run-house/runhouse) to launch on self-hosted hardware (e.g. in your own
+cloud account or on-premise cluster) but there are other options for running remotely as well. Runhouse can be installed
+with `pip install runhouse`, and you can refer to
+[hardware setup](https://runhouse-docs.readthedocs-hosted.com/en/latest/api/python/cluster.html#hardware-setup)
+for hardware setup instructions, or this
+[Colab tutorial](https://colab.research.google.com/drive/1qVwYyLTCPYPSdz9ZX7BZl9Qm0A3j7RJe) for a more in-depth walkthrough.
+
+## Simple fine-tuning script that works on TPU
+
+[finetune_lm_tpu.py](./finetune_lm_tpu.py) is a classical language modeling generation fine tuning script that has been
+adapted to run best on TPUs. It has been successfully run and tested on a TPU v5 litepod-8, and it shows how it is
+possible to perform a fine-tuning task on such hardware thanks to accelerate and FSDPv2, using transformers and Torch XLA.
+
+## Finer Examples
+
+While the first two scripts are extremely barebones when it comes to what you can do with accelerate, more advanced features are documented in two other locations.
+
+### `by_feature` examples
+
+These scripts are *individual* examples highlighting one particular feature or use-case within Accelerate. They all stem from the [nlp_example.py](./nlp_example.py) script, and any changes or modifications is denoted with a `# New Code #` comment.
+
+Read the README.md file located in the `by_feature` folder for more information.
+
+### `complete_*` examples
+
+These two scripts contain *every* single feature currently available in Accelerate in one place, as one giant script.
+
+New arguments that can be passed include:
+
+- `checkpointing_steps`, whether the various states should be saved at the end of every `n` steps, or `"epoch"` for each epoch. States are then saved to folders named `step_{n}` or `epoch_{n}`
+- `resume_from_checkpoint`, should be used if you want to resume training off of a previous call to the script and passed a `checkpointing_steps` to it.
+- `with_tracking`, should be used if you want to log the training run using all available experiment trackers in your environment. Currently supported trackers include TensorBoard, Weights and Biases, and CometML.
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/alst_ulysses_sequence_parallelism/README.md b/tasks/tasksmith-3d762a2acfee/tests/source/examples/alst_ulysses_sequence_parallelism/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..dc4ec590f856cbbbc749701c752ad46c5df8cdac
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/alst_ulysses_sequence_parallelism/README.md
@@ -0,0 +1,19 @@
+# Deepspeed's ALST/Ulysses sequence parallelism
+
+This is an example of the use of Ulysses Sequence Parallelism, which uses attention head parallelism and is part of the Arctic Long Sequence Training project at [ArcticTraining](https://github.com/snowflakedb/ArcticTraining). [This paper](https://arxiv.org/abs/2506.13996) goes into the details of this protocol.
+
+For nuances of usage please refer to the main HF Accelerate tutorial on [Context Parallelism](https://huggingface.co/docs/accelerate/en/concept_guides/context_parallelism).
+
+You need to use at least `2` gpus to enable ALST/Ulysses sequence parallelism.
+
+To run the example with `4` gpus:
+
+```bash
+bash ./sp-alst.sh
+```
+
+Change `4` to the desired sequence parallelism degree in these 2 files:
+```
+sp-alst.accelerate-config.yml:num_processes: 4
+sp-alst.py: sp_size=4,
+```
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/alst_ulysses_sequence_parallelism/sp-alst.accelerate-config.yml b/tasks/tasksmith-3d762a2acfee/tests/source/examples/alst_ulysses_sequence_parallelism/sp-alst.accelerate-config.yml
new file mode 100644
index 0000000000000000000000000000000000000000..36bcafcf070cdb41aadc3d2bda2bfee7bdd0dcb4
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/alst_ulysses_sequence_parallelism/sp-alst.accelerate-config.yml
@@ -0,0 +1,12 @@
+compute_environment: LOCAL_MACHINE
+deepspeed_config:
+ deepspeed_config_file: sp-alst.ds-config.json
+ zero3_init_flag: false
+distributed_type: DEEPSPEED
+machine_rank: 0
+main_training_function: main
+num_machines: 1
+num_processes: 4
+rdzv_backend: static
+same_network: true
+use_cpu: false
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/alst_ulysses_sequence_parallelism/sp-alst.ds-config.json b/tasks/tasksmith-3d762a2acfee/tests/source/examples/alst_ulysses_sequence_parallelism/sp-alst.ds-config.json
new file mode 100644
index 0000000000000000000000000000000000000000..3f8b0103f8c1f3afd63b9eab7e4da63b11e6cc90
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/alst_ulysses_sequence_parallelism/sp-alst.ds-config.json
@@ -0,0 +1,12 @@
+{
+ "bf16": {
+ "enabled": true
+ },
+ "zero_optimization": {
+ "stage": 3
+ },
+ "gradient_accumulation_steps": 1,
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ "seq_parallel_communication_data_type": "bf16"
+}
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/alst_ulysses_sequence_parallelism/sp-alst.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/alst_ulysses_sequence_parallelism/sp-alst.py
new file mode 100644
index 0000000000000000000000000000000000000000..87c228ca06362c9301a7e5fe27cb898f9a169068
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/alst_ulysses_sequence_parallelism/sp-alst.py
@@ -0,0 +1,155 @@
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import torch
+from deepspeed.runtime.utils import move_to_device
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+from accelerate import Accelerator
+from accelerate.utils import ParallelismConfig, set_seed
+from accelerate.utils.dataclasses import DeepSpeedSequenceParallelConfig
+
+
+set_seed(42)
+
+model_name = "TinyLlama/TinyLlama-1.1B-Chat-v1.0"
+# to run the example faster switch to the random model
+# model_name = "hf-internal-testing/tiny-random-LlamaForCausalLM"
+
+micro_batch_size = 1
+
+parallelism_config = ParallelismConfig(
+ sp_backend="deepspeed",
+ sp_size=4,
+ sp_handler=DeepSpeedSequenceParallelConfig(
+ sp_seq_length=256,
+ sp_seq_length_is_variable=True,
+ sp_attn_implementation="sdpa",
+ ),
+)
+
+accelerator = Accelerator(
+ parallelism_config=parallelism_config,
+ # log_with="wandb", # enable to log into wandb
+)
+accelerator.init_trackers(
+ project_name="ulysses-accelerate",
+ config={},
+ init_kwargs={"wandb": dict(entity="yak", name="deepspeed")},
+)
+
+tokenizer = AutoTokenizer.from_pretrained(model_name)
+model = AutoModelForCausalLM.from_pretrained(model_name)
+
+# 2 quick rough datasets to demonstrate the workings
+if 1: # real dataset
+ from datasets import load_dataset
+
+ ds = load_dataset("HuggingFaceH4/ultrachat_200k", split="train_sft[:12]")
+
+ # this is a quick example, it should be made more efficient to be used in real application
+ def convert(ex):
+ texts = tokenizer.apply_chat_template(conversation=ex["messages"], tokenize=False)
+ tokenized_dict = tokenizer(texts, max_length=256, padding=True, truncation=True)
+ return tokenized_dict
+
+ ds = ds.map(convert, batched=False, remove_columns=["prompt", "prompt_id", "messages"])
+
+ def collate_fn(batch):
+ input_ids = torch.tensor(batch[0]["input_ids"]).unsqueeze(0)
+ attention_mask = torch.tensor(batch[0]["attention_mask"]).unsqueeze(0)
+ position_ids = torch.arange(input_ids.shape[1]).unsqueeze(0)
+ return dict(
+ input_ids=input_ids,
+ position_ids=position_ids,
+ labels=input_ids,
+ attention_mask=attention_mask,
+ )
+
+ dl = torch.utils.data.DataLoader(
+ ds, batch_size=micro_batch_size, collate_fn=collate_fn, drop_last=True, shuffle=False
+ )
+
+else: # fake dataset
+ samples = 16
+ seqlen = 256
+ input_ids = torch.arange(1, seqlen * samples + 1).view(-1, seqlen) + 100
+ position_ids = torch.arange(seqlen * samples).view(-1, seqlen)
+
+ ds = torch.utils.data.TensorDataset(input_ids, position_ids)
+
+ def collate_fn(batch):
+ input_ids, position_ids = batch[0]
+ return dict(
+ input_ids=input_ids.unsqueeze(0),
+ position_ids=position_ids.unsqueeze(0),
+ labels=input_ids.unsqueeze(0),
+ )
+
+ dl = torch.utils.data.DataLoader(ds, batch_size=micro_batch_size, collate_fn=collate_fn)
+
+optimizer = torch.optim.Adam(model.parameters(), lr=1e-5)
+
+rank = torch.distributed.get_rank()
+
+if rank == 0:
+ print(f"DL orig: {len(dl)} samples")
+
+model, optimizer, dl = accelerator.prepare(model, optimizer, dl)
+
+if rank == 0:
+ print(f"DL w/ adapter: {len(dl)} samples")
+
+sp_size = parallelism_config.sp_size if parallelism_config else 1
+if sp_size > 1:
+ sp_group = accelerator.torch_device_mesh["sp"].get_group()
+ sp_world_size = parallelism_config.sp_size
+
+unwrapped_model = accelerator.unwrap_model(model)
+
+# Normal training loop
+for iter, batch in enumerate(dl):
+ optimizer.zero_grad()
+
+ if rank == 0:
+ print(f"batch {iter}: seqlen: {len(batch['input_ids'][0])}")
+ batch = move_to_device(batch, model.device)
+ outputs = model(**batch)
+
+ shift_labels = batch["shift_labels"]
+ loss = unwrapped_model.loss_function(
+ logits=outputs.logits,
+ labels=None,
+ shift_labels=shift_labels,
+ vocab_size=unwrapped_model.config.vocab_size,
+ )
+
+ if sp_size > 1:
+ # differentiable weighted per-shard-loss aggregation across ranks
+ losses_per_rank = torch.distributed.nn.functional.all_gather(loss, group=sp_group)
+ # special dealing with SFT that has prompt tokens that aren't used in loss computation
+ good_tokens = (shift_labels != -100).view(-1).sum()
+ good_tokens_per_rank = torch.distributed.nn.functional.all_gather(good_tokens, group=sp_group)
+ total_loss = sum(losses_per_rank[rank] * good_tokens_per_rank[rank] for rank in range(sp_world_size))
+ total_good_tokens = sum(good_tokens_per_rank)
+ loss = total_loss / max(total_good_tokens, 1)
+
+ if rank == 0:
+ accelerator.print(f"{iter}: {loss=}")
+ accelerator.log(dict(train_loss=loss, step=iter))
+
+ accelerator.backward(loss)
+ optimizer.step()
+
+accelerator.end_training()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/alst_ulysses_sequence_parallelism/sp-alst.sh b/tasks/tasksmith-3d762a2acfee/tests/source/examples/alst_ulysses_sequence_parallelism/sp-alst.sh
new file mode 100644
index 0000000000000000000000000000000000000000..e7e43c6d2cea363f89971440aa95a8f976224deb
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/alst_ulysses_sequence_parallelism/sp-alst.sh
@@ -0,0 +1,8 @@
+export MASTER_ADDR=localhost
+export MASTER_PORT=9998
+python -u -m accelerate.commands.launch \
+ --rdzv_conf "rdzv_backend=c10d,rdzv_endpoint=$MASTER_ADDR:$MASTER_PORT" \
+ --main_process_ip $MASTER_ADDR \
+ --main_process_port $MASTER_PORT \
+ --config_file sp-alst.accelerate-config.yml \
+ sp-alst.py
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/README.md b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..7b825dd18b3594be13e818c7b895637c3e76b6d2
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/README.md
@@ -0,0 +1,121 @@
+# What are these scripts?
+
+All scripts in this folder originate from the `nlp_example.py` file, as it is a very simplistic NLP training example using Accelerate with zero extra features.
+
+From there, each further script adds in just **one** feature of Accelerate, showing how you can quickly modify your own scripts to implement these capabilities.
+
+A full example with all of these parts integrated together can be found in the `complete_nlp_example.py` script and `complete_cv_example.py` script.
+
+Adjustments to each script from the base `nlp_example.py` file can be found quickly by searching for "# New Code #"
+
+## Example Scripts by Feature and their Arguments
+
+### Base Example (`../nlp_example.py`)
+
+- Shows how to use `Accelerator` in an extremely simplistic PyTorch training loop
+- Arguments available:
+ - `mixed_precision`, whether to use mixed precision. ("no", "fp16", or "bf16")
+ - `cpu`, whether to train using only the CPU. (yes/no/1/0)
+
+All following scripts also accept these arguments in addition to their added ones.
+
+These arguments should be added at the end of any method for starting the python script (such as `python`, `accelerate launch`, `python -m torch.distributed.run`), such as:
+
+```bash
+accelerate launch ../nlp_example.py --mixed_precision fp16 --cpu 0
+```
+
+### Checkpointing and Resuming Training (`checkpointing.py`)
+
+- Shows how to use `Accelerator.save_state` and `Accelerator.load_state` to save or continue training
+- **It is assumed you are continuing off the same training script**
+- Arguments available:
+ - `checkpointing_steps`, after how many steps the various states should be saved. ("epoch", 1, 2, ...)
+ - `output_dir`, where saved state folders should be saved to, default is current working directory
+ - `resume_from_checkpoint`, what checkpoint folder to resume from. ("epoch_0", "step_22", ...)
+
+These arguments should be added at the end of any method for starting the python script (such as `python`, `accelerate launch`, `python -m torchrun`), such as:
+
+(Note, `resume_from_checkpoint` assumes that we've ran the script for one epoch with the `--checkpointing_steps epoch` flag)
+
+```bash
+accelerate launch ./checkpointing.py --checkpointing_steps epoch output_dir "checkpointing_tutorial" --resume_from_checkpoint "checkpointing_tutorial/epoch_0"
+```
+
+### Cross Validation (`cross_validation.py`)
+
+- Shows how to use `Accelerator.free_memory` and run cross validation efficiently with `datasets`.
+- Arguments available:
+ - `num_folds`, the number of folds the training dataset should be split into.
+
+These arguments should be added at the end of any method for starting the python script (such as `python`, `accelerate launch`, `python -m torchrun`), such as:
+
+```bash
+accelerate launch ./cross_validation.py --num_folds 2
+```
+
+### Experiment Tracking (`tracking.py`)
+
+- Shows how to use `Accelerate.init_trackers` and `Accelerator.log`
+- Can be used with Weights and Biases, TensorBoard, or CometML.
+- Arguments available:
+ - `with_tracking`, whether to load in all available experiment trackers from the environment.
+
+These arguments should be added at the end of any method for starting the python script (such as `python`, `accelerate launch`, `python -m torchrun`), such as:
+
+```bash
+accelerate launch ./tracking.py --with_tracking
+```
+
+### Gradient Accumulation (`gradient_accumulation.py`)
+
+- Shows how to use `Accelerator.no_sync` to prevent gradient averaging in a distributed setup.
+- Arguments available:
+ - `gradient_accumulation_steps`, the number of steps to perform before the gradients are accumulated and the optimizer and scheduler are stepped + zero_grad
+
+These arguments should be added at the end of any method for starting the python script (such as `python`, `accelerate launch`, `python -m torchrun`), such as:
+
+```bash
+accelerate launch ./gradient_accumulation.py --gradient_accumulation_steps 5
+```
+
+### LocalSGD (`local_sgd.py`)
+- Shows how to use `Accelerator.no_sync` to prevent gradient averaging in a distributed setup. However, unlike gradient accumulation, this method does not change the effective batch size. Local SGD can be combined with gradient accumulation.
+
+These arguments should be added at the end of any method for starting the python script (such as `python`, `accelerate launch`, `python -m torchrun`), such as:
+
+```bash
+accelerate launch ./local_sgd.py --local_sgd_steps 4
+```
+
+### DDP Communication Hook (`ddp_comm_hook.py`)
+
+- Shows how to use DDP Communication Hooks to control and optimize gradient communication across workers in a DistributedDataParallel setup.
+- Arguments available:
+ - `ddp_comm_hook`, the type of DDP communication hook to use. Choose between `no`, `fp16`, `bf16`, `power_sgd`, and `batched_power_sgd`.
+
+These arguments should be added at the end of any method for starting the python script (such as `accelerate launch`, `python -m torch.distributed.run`), such as:
+
+```bash
+accelerate launch ./ddp_comm_hook.py --mixed_precision fp16 --ddp_comm_hook power_sgd
+```
+
+### Profiler (`profiler.py`)
+
+- Shows how to use the profiling capabilities of `Accelerate` to profile PyTorch models during training.
+- Uses the `ProfileKwargs` handler to customize profiling options, including activities, scheduling, and additional profiling options.
+- Can generate and save profiling traces in JSON format for visualization in Chrome's tracing tool.
+
+Arguments available:
+- `--record_shapes`: If passed, records shapes for profiling.
+- `--profile_memory`: If passed, profiles memory usage.
+- `--with_stack`: If passed, profiles stack traces.
+- `--with_flops`: If passed, profiles floating point operations (FLOPS).
+- `--output_trace_dir`: If specified, saves the profiling trace to the given dir in JSON format.
+- `--cpu`: If passed, trains on the CPU instead of GPU.
+
+These arguments should be added at the end of any method for starting the Python script (such as `python`, `accelerate launch`, `python -m torchrun`), such as:
+
+```bash
+accelerate launch ./profiler.py --record_shapes --profile_memory --with_flops --output_trace_dir "profiler"
+```
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/automatic_gradient_accumulation.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/automatic_gradient_accumulation.py
new file mode 100644
index 0000000000000000000000000000000000000000..c610f7704c301d372074b5fcd289e9df4653cf9f
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/automatic_gradient_accumulation.py
@@ -0,0 +1,243 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import os
+
+# New Code #
+import evaluate
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup, set_seed
+
+from accelerate import Accelerator
+from accelerate.utils import find_executable_batch_size
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate,
+# specifically showcasing how to combine both the gradient accumulation
+# and automatic batch size finder utilities of Accelerate to perfrom
+# automatic gradient accumulation
+#
+# This example trains a Bert base model on GLUE MRPC
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# New additions from the base script can be found quickly by
+# looking for the # New Code # tags
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+EVAL_BATCH_SIZE = 32
+
+
+def get_dataloaders(accelerator: Accelerator, batch_size: int = 16):
+ """
+ Creates a set of `DataLoader`s for the `glue` dataset,
+ using "bert-base-cased" as the tokenizer.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ """
+ tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+# For testing only
+if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ from accelerate.test_utils.training import mocked_dataloaders
+
+ get_dataloaders = mocked_dataloaders # noqa: F811
+
+
+def training_function(config, args):
+ # For testing only
+ if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ config["num_epochs"] = 2
+ # Initialize accelerator
+ accelerator = Accelerator(cpu=args.cpu, mixed_precision=args.mixed_precision)
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ observed_batch_size = int(config["batch_size"])
+
+ metric = evaluate.load("glue", "mrpc")
+
+ # New Code #
+ # We use the `find_executable_batch_size` decorator, passing in the desired observed batch size
+ # to train on. If a CUDA OOM error occurs, it will retry this loop cutting the batch size in
+ # half each time. From this, we can calculate the number of gradient accumulation steps needed
+ # and modify the Accelerator object as a result
+ @find_executable_batch_size(starting_batch_size=int(observed_batch_size))
+ def inner_training_loop(batch_size):
+ # Since we need to modify the outside accelerator object, we need to bring it
+ # to the local scope
+ nonlocal accelerator
+
+ # We can calculate the number of gradient accumulation steps based on the current
+ # batch size vs the starting batch size
+ num_gradient_accumulation_steps = observed_batch_size // batch_size
+
+ # And then set it in the Accelerator directly:
+ accelerator.gradient_accumulation_steps = num_gradient_accumulation_steps
+
+ # Next we need to free all of the stored model references in the Accelerator each time
+ accelerator.free_memory()
+
+ # And set the seed so our results are reproducable each reset
+ set_seed(seed)
+
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", return_dict=True)
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+
+ # Instantiate optimizer
+ optimizer = AdamW(params=model.parameters(), lr=lr)
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size)
+
+ # Instantiate scheduler
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=100,
+ num_training_steps=(len(train_dataloader) * num_epochs),
+ )
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # Now we train the model
+ for epoch in range(num_epochs):
+ model.train()
+ for step, batch in enumerate(train_dataloader):
+ # And perform gradient accumulation
+ with accelerator.accumulate(model):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ outputs = model(**batch)
+ loss = outputs.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+
+ # New Code #
+ # And call it at the end with no arguments
+ # Note: You could also refactor this outside of your training loop function
+ inner_training_loop()
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ args = parser.parse_args()
+ # New Code #
+ # We modify the starting batch size to be an observed batch size of 256, to guarentee an initial CUDA OOM
+ config = {"lr": 2e-5, "num_epochs": 3, "seed": 42, "batch_size": 256}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/checkpointing.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/checkpointing.py
new file mode 100644
index 0000000000000000000000000000000000000000..218f4a50914b85d1d29ddfb6e1f0e33246b90be5
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/checkpointing.py
@@ -0,0 +1,326 @@
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import os
+
+import evaluate
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup
+
+from accelerate import Accelerator, DataLoaderConfiguration, DistributedType
+from accelerate.utils import set_seed
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate,
+# specifically showcasing the checkpointing capability,
+# and builds off the `nlp_example.py` script.
+#
+# This example trains a Bert base model on GLUE MRPC
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# To help focus on the differences in the code, building `DataLoaders`
+# was refactored into its own function.
+# New additions from the base script can be found quickly by
+# looking for the # New Code # tags
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+
+def get_dataloaders(accelerator: Accelerator, batch_size: int = 16):
+ """
+ Creates a set of `DataLoader`s for the `glue` dataset,
+ using "bert-base-cased" as the tokenizer.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ """
+ tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ max_length = 128 if accelerator.distributed_type == DistributedType.XLA else None
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+# For testing only
+if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ from accelerate.test_utils.training import mocked_dataloaders
+
+ get_dataloaders = mocked_dataloaders # noqa: F811
+
+
+def training_function(config, args):
+ # For testing only
+ if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ config["num_epochs"] = 2
+ # Initialize accelerator
+ dataloader_config = DataLoaderConfiguration(use_stateful_dataloader=args.use_stateful_dataloader)
+ accelerator = Accelerator(cpu=args.cpu, mixed_precision=args.mixed_precision, dataloader_config=dataloader_config)
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+
+ # New Code #
+ # Parse out whether we are saving every epoch or after a certain number of batches
+ if hasattr(args.checkpointing_steps, "isdigit"):
+ if args.checkpointing_steps == "epoch":
+ checkpointing_steps = args.checkpointing_steps
+ elif args.checkpointing_steps.isdigit():
+ checkpointing_steps = int(args.checkpointing_steps)
+ else:
+ raise ValueError(
+ f"Argument `checkpointing_steps` must be either a number or `epoch`. `{args.checkpointing_steps}` passed."
+ )
+ else:
+ checkpointing_steps = None
+
+ set_seed(seed)
+
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size)
+ metric = evaluate.load("glue", "mrpc")
+
+ # If the batch size is too big we use gradient accumulation
+ gradient_accumulation_steps = 1
+ if batch_size > MAX_GPU_BATCH_SIZE and accelerator.distributed_type != DistributedType.XLA:
+ gradient_accumulation_steps = batch_size // MAX_GPU_BATCH_SIZE
+ batch_size = MAX_GPU_BATCH_SIZE
+
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", return_dict=True)
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+
+ # Instantiate optimizer
+ optimizer = AdamW(params=model.parameters(), lr=lr)
+
+ # Instantiate scheduler
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=100,
+ num_training_steps=(len(train_dataloader) * num_epochs) // gradient_accumulation_steps,
+ )
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # New Code #
+ # We need to keep track of how many total steps we have iterated over
+ overall_step = 0
+ # We also need to keep track of the stating epoch so files are named properly
+ starting_epoch = 0
+
+ # We need to load the checkpoint back in before training here with `load_state`
+ # The total number of epochs is adjusted based on where the state is being loaded from,
+ # as we assume continuation of the same training script
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ accelerator.print(f"Resumed from checkpoint: {args.resume_from_checkpoint}")
+ accelerator.load_state(args.resume_from_checkpoint)
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ else:
+ resume_step = int(training_difference.replace("step_", ""))
+ starting_epoch = resume_step // len(train_dataloader)
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # Now we train the model
+ for epoch in range(starting_epoch, num_epochs):
+ model.train()
+ # New Code #
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We need to skip steps until we reach the resumed step only if we are not using a stateful dataloader
+ if not args.use_stateful_dataloader:
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+ overall_step += resume_step
+ else:
+ # After the first iteration though, we need to go back to the original dataloader
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss = loss / gradient_accumulation_steps
+ accelerator.backward(loss)
+ if step % gradient_accumulation_steps == 0:
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ # New Code #
+ overall_step += 1
+
+ # New Code #
+ # We save the model, optimizer, lr_scheduler, and seed states by calling `save_state`
+ # These are saved to folders named `step_{overall_step}`
+ # Will contain files: "pytorch_model.bin", "optimizer.bin", "scheduler.bin", and "random_states.pkl"
+ # If mixed precision was used, will also save a "scalar.bin" file
+ if isinstance(checkpointing_steps, int):
+ output_dir = f"step_{overall_step}"
+ if overall_step % checkpointing_steps == 0:
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+ model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True` (the default).
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+ eval_metric = metric.compute()
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+
+ # New Code #
+ # We save the model, optimizer, lr_scheduler, and seed states by calling `save_state`
+ # These are saved to folders named `epoch_{epoch}`
+ # Will contain files: "pytorch_model.bin", "optimizer.bin", "scheduler.bin", and "random_states.pkl"
+ # If mixed precision was used, will also save a "scalar.bin" file
+ if checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--output_dir",
+ type=str,
+ default=".",
+ help="Optional save directory where all checkpoint folders will be stored. Default is the current working directory.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--use_stateful_dataloader",
+ action="store_true",
+ help="If the dataloader should be a resumable stateful dataloader.",
+ )
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": 3, "seed": 42, "batch_size": 16}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/cross_validation.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/cross_validation.py
new file mode 100644
index 0000000000000000000000000000000000000000..162034287c751291fdf6aa7b6e79b0a918ddcbd0
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/cross_validation.py
@@ -0,0 +1,280 @@
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+
+import evaluate
+import numpy as np
+import torch
+from datasets import DatasetDict, load_dataset
+
+# New Code #
+# We'll be using StratifiedKFold for this example
+from sklearn.model_selection import StratifiedKFold
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup, set_seed
+
+from accelerate import Accelerator, DistributedType
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate,
+# specifically showcasing how to perform Cross Validation,
+# and builds off the `nlp_example.py` script.
+#
+# This example trains a Bert base model on GLUE MRPC
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# To help focus on the differences in the code, building `DataLoaders`
+# was refactored into its own function.
+# New additions from the base script can be found quickly by
+# looking for the # New Code # tags
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+# New Code #
+# We need a different `get_dataloaders` function that will build dataloaders by index
+
+
+def get_fold_dataloaders(
+ accelerator: Accelerator, dataset: DatasetDict, train_idxs: list[int], valid_idxs: list[int], batch_size: int = 16
+):
+ """
+ Gets a set of train, valid, and test dataloaders for a particular fold
+
+ Args:
+ accelerator (`Accelerator`):
+ The main `Accelerator` object
+ train_idxs (list of `int`):
+ The split indices for the training dataset
+ valid_idxs (list of `int`):
+ The split indices for the validation dataset
+ batch_size (`int`):
+ The size of the minibatch. Default is 16
+ """
+ tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
+ datasets = DatasetDict(
+ {
+ "train": dataset["train"].select(train_idxs),
+ "validation": dataset["train"].select(valid_idxs),
+ "test": dataset["validation"],
+ }
+ )
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ max_length = 128 if accelerator.distributed_type == DistributedType.XLA else None
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ test_dataloader = DataLoader(
+ tokenized_datasets["test"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ return train_dataloader, eval_dataloader, test_dataloader
+
+
+def training_function(config, args):
+ # New Code #
+ test_predictions = []
+ # Download the dataset
+ datasets = load_dataset("glue", "mrpc")
+ # Create our splits
+ kfold = StratifiedKFold(n_splits=int(args.num_folds))
+ # Initialize accelerator
+ accelerator = Accelerator(cpu=args.cpu, mixed_precision=args.mixed_precision)
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+
+ metric = evaluate.load("glue", "mrpc")
+
+ # If the batch size is too big we use gradient accumulation
+ gradient_accumulation_steps = 1
+ if batch_size > MAX_GPU_BATCH_SIZE and accelerator.distributed_type != DistributedType.XLA:
+ gradient_accumulation_steps = batch_size // MAX_GPU_BATCH_SIZE
+ batch_size = MAX_GPU_BATCH_SIZE
+
+ set_seed(seed)
+
+ # New Code #
+ # Create our folds:
+ folds = kfold.split(np.zeros(datasets["train"].num_rows), datasets["train"]["label"])
+ test_references = []
+ # Iterate over them
+ for i, (train_idxs, valid_idxs) in enumerate(folds):
+ train_dataloader, eval_dataloader, test_dataloader = get_fold_dataloaders(
+ accelerator,
+ datasets,
+ train_idxs,
+ valid_idxs,
+ )
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", return_dict=True)
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+
+ # Instantiate optimizer
+ optimizer = AdamW(params=model.parameters(), lr=lr)
+
+ # Instantiate scheduler
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=100,
+ num_training_steps=(len(train_dataloader) * num_epochs) // gradient_accumulation_steps,
+ )
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # Now we train the model
+ for epoch in range(num_epochs):
+ model.train()
+ for step, batch in enumerate(train_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss = loss / gradient_accumulation_steps
+ accelerator.backward(loss)
+ if step % gradient_accumulation_steps == 0:
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+
+ # New Code #
+ # We also run predictions on the test set at the very end
+ fold_predictions = []
+ for step, batch in enumerate(test_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ fold_predictions.append(predictions.cpu())
+ if i == 0:
+ # We need all of the test predictions
+ test_references.append(references.cpu())
+ # Use accelerator.print to print only on the main process.
+ test_predictions.append(torch.cat(fold_predictions, dim=0))
+ # We now need to release all our memory and get rid of the current model, optimizer, etc
+ model, optimizer = accelerator.free_memory(model, optimizer)
+ # New Code #
+ # Finally we check the accuracy of our folded results:
+ test_references = torch.cat(test_references, dim=0)
+ preds = torch.stack(test_predictions, dim=0).sum(dim=0).div(int(args.num_folds)).argmax(dim=-1)
+ test_metric = metric.compute(predictions=preds, references=test_references)
+ accelerator.print("Average test metrics from all folds:", test_metric)
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ # New Code #
+ parser.add_argument("--num_folds", type=int, default=3, help="The number of splits to perform across the dataset")
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": 3, "seed": 42, "batch_size": 16}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/ddp_comm_hook.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/ddp_comm_hook.py
new file mode 100644
index 0000000000000000000000000000000000000000..d7028b597939a5e3d4bb2bc4a589de26f53a9da5
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/ddp_comm_hook.py
@@ -0,0 +1,232 @@
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import os
+
+import evaluate
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup, set_seed
+
+from accelerate import Accelerator, DistributedType
+from accelerate.utils import DDPCommunicationHookType, DistributedDataParallelKwargs
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate
+# and perform ddp communication hook
+#
+# This example trains a Bert base model on GLUE MRPC
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+
+def get_dataloaders(accelerator: Accelerator, batch_size: int = 16):
+ """
+ Creates a set of `DataLoader`s for the `glue` dataset,
+ using "bert-base-cased" as the tokenizer.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ """
+ tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ max_length = 128 if accelerator.distributed_type == DistributedType.XLA else None
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+# For testing only
+if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ from accelerate.test_utils.training import mocked_dataloaders
+
+ get_dataloaders = mocked_dataloaders # noqa: F811
+
+
+def training_function(config, args):
+ # For testing only
+ if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ config["num_epochs"] = 2
+ # New Code #
+ ddp_comm_hook_type = DDPCommunicationHookType(args.ddp_comm_hook)
+ ddp_comm_wrapper = DDPCommunicationHookType(args.ddp_comm_wrapper)
+ ddp_kwargs = DistributedDataParallelKwargs(comm_hook=ddp_comm_hook_type, comm_wrapper=ddp_comm_wrapper)
+ # Initialize accelerator
+ accelerator = Accelerator(cpu=args.cpu, mixed_precision=args.mixed_precision, kwargs_handlers=[ddp_kwargs])
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+
+ metric = evaluate.load("glue", "mrpc")
+
+ set_seed(seed)
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size)
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", return_dict=True)
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+
+ # Instantiate optimizer
+ optimizer = AdamW(params=model.parameters(), lr=lr)
+
+ # Instantiate scheduler
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=100,
+ num_training_steps=(len(train_dataloader) * num_epochs),
+ )
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # Now we train the model
+ for epoch in range(num_epochs):
+ model.train()
+ for step, batch in enumerate(train_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ # We use the new `accumulate` context manager to perform gradient accumulation
+ with accelerator.accumulate(model):
+ output = model(**batch)
+ loss = output.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+ # New Code #
+ parser.add_argument(
+ "--ddp_comm_hook",
+ type=str,
+ default="no",
+ choices=["no", "fp16", "bf16", "power_sgd", "batched_power_sgd"],
+ help="DDP Communication hook to use. Choose between `no`, `fp16`, `bf16`, `power_sgd`, and `batched_power_sgd`.",
+ )
+ # New Code #
+ parser.add_argument(
+ "--ddp_comm_wrapper",
+ type=str,
+ default="no",
+ choices=["no", "fp16", "bf16"],
+ help="DDP Communication wrapper to use. Choose between `no`, `fp16`, and `bf16`.",
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": 3, "seed": 42, "batch_size": 16}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/deepspeed_with_config_support.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/deepspeed_with_config_support.py
new file mode 100644
index 0000000000000000000000000000000000000000..c7dcbf1ae6ade98fbbd087cae9bd6ec84d8a4f49
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/deepspeed_with_config_support.py
@@ -0,0 +1,723 @@
+#!/usr/bin/env python
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for causal language modeling (GPT, GPT-2, CTRL, ...)
+on a text file or a dataset without using HuggingFace Trainer.
+
+Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
+https://huggingface.co/models?filter=text-generation
+"""
+# You can also adapt this script on your own causal language modeling task. Pointers for this are left as comments.
+
+import argparse
+import json
+import logging
+import math
+import os
+import random
+from itertools import chain
+from pathlib import Path
+
+import datasets
+import torch
+import transformers
+from datasets import load_dataset
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from tqdm.auto import tqdm
+from transformers import (
+ CONFIG_MAPPING,
+ MODEL_MAPPING,
+ AutoConfig,
+ AutoModelForCausalLM,
+ AutoTokenizer,
+ SchedulerType,
+ default_data_collator,
+ get_scheduler,
+)
+from transformers.utils.versions import require_version
+
+from accelerate import Accelerator, DistributedType
+from accelerate.logging import get_logger
+from accelerate.utils import DummyOptim, DummyScheduler, set_seed
+
+
+logger = get_logger(__name__)
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
+
+MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Finetune a transformers model on a causal language modeling task")
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ default=None,
+ help="The name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--dataset_config_name",
+ type=str,
+ default=None,
+ help="The configuration name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
+ )
+ parser.add_argument(
+ "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
+ )
+ parser.add_argument(
+ "--validation_split_percentage",
+ default=5,
+ help="The percentage of the train set used as validation set in case there's no validation split",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=False,
+ )
+ parser.add_argument(
+ "--config_name",
+ type=str,
+ default=None,
+ help="Pretrained config name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ type=str,
+ default=None,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--use_slow_tokenizer",
+ action="store_true",
+ help="If passed, will use a slow tokenizer (not backed by the 🤗 Tokenizers library).",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument(
+ "--model_type",
+ type=str,
+ default=None,
+ help="Model type to use if training from scratch.",
+ choices=MODEL_TYPES,
+ )
+ parser.add_argument(
+ "--block_size",
+ type=int,
+ default=None,
+ help=(
+ "Optional input sequence length after tokenization. The training dataset will be truncated in block of"
+ " this size for training. Default to the model max input length for single sentence inputs (take into"
+ " account special tokens)."
+ ),
+ )
+ parser.add_argument(
+ "--preprocessing_num_workers",
+ type=int,
+ default=None,
+ help="The number of processes to use for the preprocessing.",
+ )
+ parser.add_argument(
+ "--overwrite_cache", type=bool, default=False, help="Overwrite the cached training and evaluation sets"
+ )
+ parser.add_argument(
+ "--no_keep_linebreaks", action="store_true", help="Do not keep line breaks when using TXT files."
+ )
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ # New Code #
+ # Whether to load the best model at the end of training
+ parser.add_argument(
+ "--load_best_model",
+ action="store_true",
+ help="Whether to load the best model at the end of training",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"`, `"dvclive"`, and `"swanlab"`. Use `"all"` (default) to report to all integrations.'
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+ if args.dataset_name is None and args.train_file is None and args.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if args.train_file is not None:
+ extension = args.train_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, json or txt file."
+ if args.validation_file is not None:
+ extension = args.validation_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, json or txt file."
+
+ if args.push_to_hub:
+ assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
+
+ return args
+
+
+# New Code #
+def evaluate(args, model, eval_dataloader, accelerator, eval_dataset):
+ model.eval()
+ losses = []
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+
+ loss = outputs.loss
+ losses.append(accelerator.gather_for_metrics(loss.repeat(args.per_device_eval_batch_size)))
+
+ losses = torch.cat(losses)
+ try:
+ eval_loss = torch.mean(losses)
+ perplexity = math.exp(eval_loss)
+ except OverflowError:
+ perplexity = float("inf")
+ return perplexity, eval_loss
+
+
+def main():
+ args = parse_args()
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+
+ # when using DeepSpeed, the `gradient_accumulation_steps` is properly set from the DeepSpeed plugin/config
+ # or from `accelerate launch` via `--gradient_accumulation_steps` else
+ # defaulting to the passed `args.gradient_accumulation_steps`
+ accelerator = (
+ Accelerator(
+ log_with=args.report_to,
+ project_dir=args.output_dir,
+ gradient_accumulation_steps=args.gradient_accumulation_steps,
+ )
+ if args.with_tracking
+ else Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps)
+ )
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ api = HfApi(token=args.hub_token)
+
+ # Create repo (repo_name from args or inferred)
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ repo_id = api.create_repo(repo_name, exist_ok=True).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(args.dataset_name, args.dataset_config_name)
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ args.dataset_name,
+ args.dataset_config_name,
+ split=f"train[:{args.validation_split_percentage}%]",
+ )
+ raw_datasets["train"] = load_dataset(
+ args.dataset_name,
+ args.dataset_config_name,
+ split=f"train[{args.validation_split_percentage}%:]",
+ )
+ else:
+ data_files = {}
+ dataset_args = {}
+ if args.train_file is not None:
+ data_files["train"] = args.train_file
+ if args.validation_file is not None:
+ data_files["validation"] = args.validation_file
+ extension = args.train_file.split(".")[-1]
+ if extension == "txt":
+ extension = "text"
+ dataset_args["keep_linebreaks"] = not args.no_keep_linebreaks
+ raw_datasets = load_dataset(extension, data_files=data_files, **dataset_args)
+ # If no validation data is there, validation_split_percentage will be used to divide the dataset.
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[:{args.validation_split_percentage}%]",
+ **dataset_args,
+ )
+ raw_datasets["train"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[{args.validation_split_percentage}%:]",
+ **dataset_args,
+ )
+
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.html.
+
+ # Load pretrained model and tokenizer
+ #
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ if args.config_name:
+ config = AutoConfig.from_pretrained(args.config_name)
+ elif args.model_name_or_path:
+ config = AutoConfig.from_pretrained(args.model_name_or_path)
+ else:
+ config = CONFIG_MAPPING[args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ if args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(args.tokenizer_name, use_fast=not args.use_slow_tokenizer)
+ elif args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path, use_fast=not args.use_slow_tokenizer)
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script."
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if args.model_name_or_path:
+ model = AutoModelForCausalLM.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = AutoModelForCausalLM.from_config(config)
+
+ model.resize_token_embeddings(len(tokenizer))
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ column_names = raw_datasets["train"].column_names
+ text_column_name = "text" if "text" in column_names else column_names[0]
+
+ def tokenize_function(examples):
+ return tokenizer(examples[text_column_name])
+
+ with accelerator.main_process_first():
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Running tokenizer on dataset",
+ )
+
+ if args.block_size is None:
+ block_size = tokenizer.model_max_length
+ if block_size > 1024:
+ logger.warning(
+ f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
+ "Picking 1024 instead. You can change that default value by passing --block_size xxx."
+ )
+ block_size = 1024
+ else:
+ if args.block_size > tokenizer.model_max_length:
+ logger.warning(
+ f"The block_size passed ({args.block_size}) is larger than the maximum length for the model"
+ f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
+ )
+ block_size = min(args.block_size, tokenizer.model_max_length)
+
+ # Main data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
+ def group_texts(examples):
+ # Concatenate all texts.
+ concatenated_examples = {k: list(chain(*examples[k])) for k in examples.keys()}
+ total_length = len(concatenated_examples[list(examples.keys())[0]])
+ # We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
+ # customize this part to your needs.
+ if total_length >= block_size:
+ total_length = (total_length // block_size) * block_size
+ # Split by chunks of max_len.
+ result = {
+ k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
+ for k, t in concatenated_examples.items()
+ }
+ result["labels"] = result["input_ids"].copy()
+ return result
+
+ # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
+ # for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
+ # to preprocess.
+ #
+ # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
+ # https://huggingface.co/docs/datasets/package_reference/main_classes.html#datasets.Dataset.map
+
+ with accelerator.main_process_first():
+ lm_datasets = tokenized_datasets.map(
+ group_texts,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ load_from_cache_file=not args.overwrite_cache,
+ desc=f"Grouping texts in chunks of {block_size}",
+ )
+
+ train_dataset = lm_datasets["train"]
+ eval_dataset = lm_datasets["validation"]
+
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ # DataLoaders creation:
+ train_dataloader = DataLoader(
+ train_dataset, shuffle=True, collate_fn=default_data_collator, batch_size=args.per_device_train_batch_size
+ )
+ eval_dataloader = DataLoader(
+ eval_dataset, collate_fn=default_data_collator, batch_size=args.per_device_eval_batch_size
+ )
+
+ # Optimizer
+ # Split weights in two groups, one with weight decay and the other not.
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ # New Code #
+ # Creates Dummy Optimizer if `optimizer` was specified in the config file else creates Adam Optimizer
+ optimizer_cls = (
+ torch.optim.AdamW
+ if accelerator.state.deepspeed_plugin is None
+ or "optimizer" not in accelerator.state.deepspeed_plugin.deepspeed_config
+ else DummyOptim
+ )
+ optimizer = optimizer_cls(optimizer_grouped_parameters, lr=args.learning_rate)
+
+ # On TPU, the tie weights in our model have been disconnected, so we need to restore the ties.
+ if accelerator.distributed_type == DistributedType.XLA:
+ model.tie_weights()
+
+ # Scheduler and math around the number of training steps.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / accelerator.gradient_accumulation_steps)
+ overrode_max_train_steps = False
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+ else:
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # New Code #
+ # Creates Dummy Scheduler if `scheduler` was specified in the config file else creates `args.lr_scheduler_type` Scheduler
+ if (
+ accelerator.state.deepspeed_plugin is None
+ or "scheduler" not in accelerator.state.deepspeed_plugin.deepspeed_config
+ ):
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps,
+ num_training_steps=args.max_train_steps,
+ )
+ else:
+ lr_scheduler = DummyScheduler(
+ optimizer, total_num_steps=args.max_train_steps, warmup_num_steps=args.num_warmup_steps
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / accelerator.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("clm_no_trainer", experiment_config)
+
+ # Train!
+ total_batch_size = (
+ args.per_device_train_batch_size * accelerator.num_processes * accelerator.gradient_accumulation_steps
+ )
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {accelerator.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+ best_metric = None
+ best_metric_checkpoint = None
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ accelerator.load_state(args.resume_from_checkpoint)
+ accelerator.print(f"Resumed from checkpoint: {args.resume_from_checkpoint}")
+ path = os.path.basename(args.resume_from_checkpoint)
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ resume_step = int(training_difference.replace("step_", ""))
+ starting_epoch = resume_step // num_update_steps_per_epoch
+ resume_step -= starting_epoch * num_update_steps_per_epoch
+ completed_steps = resume_step
+
+ # update progress bar if resumed from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+
+ # skip new `skip_first_batches` to skip the batches when resuming from ckpt
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We need to skip steps until we reach the resumed step
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ # After the first iteration though, we need to go back to the original dataloader
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ # In particular, DeepSpeed handles `gradient_accumulation` via `DeepSpeedEngine`.
+ # Below, we use `accelerator.accumulate` if the user
+ # wants to switch to other approaches such as plain DDP, PyTorch FSDP ...
+ # This avoids having to change any code as things are all handled across different distributed setups.
+ with accelerator.accumulate(model):
+ outputs = model(**batch)
+ loss = outputs.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ if accelerator.sync_gradients:
+ progress_bar.update(1)
+ completed_steps += 1
+
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ step_loss = accelerator.reduce(loss.detach().clone()).item()
+ total_loss += step_loss
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+ if completed_steps >= args.max_train_steps:
+ break
+
+ perplexity, eval_loss = evaluate(args, model, eval_dataloader, accelerator, eval_dataset)
+ logger.info(f"epoch {epoch}: perplexity: {perplexity} eval_loss: {eval_loss}")
+
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "perplexity": perplexity,
+ "eval_loss": eval_loss,
+ "train_loss": total_loss / len(train_dataloader),
+ "epoch": epoch,
+ "step": completed_steps,
+ },
+ step=completed_steps,
+ )
+
+ if isinstance(checkpointing_steps, str) and checkpointing_steps == "epoch":
+ accelerator.save_state(os.path.join(args.output_dir, f"epoch_{epoch}"))
+
+ # New Code #
+ # Tracks the best checkpoint and best metric
+ if best_metric is None or best_metric > perplexity:
+ best_metric = perplexity
+ best_metric_checkpoint = os.path.join(args.output_dir, "best_checkpoint")
+ accelerator.save_state(best_metric_checkpoint)
+ accelerator.print(f"New best metric: {best_metric} at epoch {epoch}")
+ accelerator.print(f"best_metric_checkpoint: {best_metric_checkpoint}")
+
+ # New Code #
+ # Loads the best checkpoint after the training is finished
+ if args.load_best_model:
+ accelerator.load_state(best_metric_checkpoint)
+
+ # New Code #
+ # Evaluates using the best checkpoint
+ perplexity, eval_loss = evaluate(args, model, eval_dataloader, accelerator, eval_dataset)
+ logger.info(f"Best model metrics: perplexity: {perplexity} eval_loss: {eval_loss}")
+ if perplexity != best_metric:
+ raise AssertionError(
+ f"Best metric {best_metric} does not match the metric {perplexity} of the loaded best model."
+ )
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+
+ # New Code #
+ # Saves the whole/unpartitioned fp16 model when in ZeRO Stage-3 to the output directory if
+ # `stage3_gather_16bit_weights_on_model_save` is True in DeepSpeed Config file or
+ # `zero3_save_16bit_model` is True in DeepSpeed Plugin.
+ # For Zero Stages 1 and 2, models are saved as usual in the output directory.
+ # The model name saved is `pytorch_model.bin`
+ unwrapped_model.save_pretrained(
+ args.output_dir,
+ is_main_process=accelerator.is_main_process,
+ save_function=accelerator.save,
+ state_dict=accelerator.get_state_dict(model),
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ if args.push_to_hub:
+ api.upload_folder(
+ repo_id=repo_id,
+ folder_path=args.output_dir,
+ commit_message="End of training",
+ )
+
+ with open(os.path.join(args.output_dir, "all_results.json"), "w") as f:
+ json.dump({"perplexity": perplexity, "eval_loss": eval_loss.item()}, f)
+ accelerator.end_training()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/early_stopping.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/early_stopping.py
new file mode 100644
index 0000000000000000000000000000000000000000..12e087d891fad40d3ce0515e226c39e561d19f55
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/early_stopping.py
@@ -0,0 +1,246 @@
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+
+import evaluate
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup, set_seed
+
+from accelerate import Accelerator, DistributedType
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate
+# specifically showcasing how to perform early stopping,
+# and builds off the `nlp_example.py` script
+#
+# This example trains a Bert base model on GLUE MRPC
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+
+def get_dataloaders(accelerator: Accelerator, batch_size: int = 16):
+ """
+ Creates a set of `DataLoader`s for the `glue` dataset,
+ using "bert-base-cased" as the tokenizer.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ """
+ tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ max_length = 128 if accelerator.distributed_type == DistributedType.XLA else None
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size, drop_last=True
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"],
+ shuffle=False,
+ collate_fn=collate_fn,
+ batch_size=EVAL_BATCH_SIZE,
+ drop_last=(accelerator.mixed_precision == "fp8"),
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+# New code
+class EarlyStoppingCallback:
+ "A callback class that helps with early stopping"
+
+ def __init__(self, min_delta=0, patience=5):
+ self.min_delta = min_delta
+ self.patience = patience
+ self.counter = 0
+ self.lowest_loss = float("inf")
+
+ def check_early_stopping(self, eval_loss):
+ delta = self.lowest_loss - eval_loss
+ if delta >= self.min_delta:
+ self.lowest_loss = eval_loss
+ self.counter = 0
+ else:
+ self.counter += 1
+ if self.counter >= self.patience:
+ return True
+ return False
+
+
+callback = EarlyStoppingCallback()
+
+
+def training_function(config, args):
+ # Initialize accelerator
+ accelerator = Accelerator(cpu=args.cpu, mixed_precision=args.mixed_precision)
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+
+ metric = evaluate.load("glue", "mrpc")
+
+ # If the batch size is too big we use gradient accumulation
+ gradient_accumulation_steps = 1
+ if batch_size > MAX_GPU_BATCH_SIZE and accelerator.distributed_type != DistributedType.XLA:
+ gradient_accumulation_steps = batch_size // MAX_GPU_BATCH_SIZE
+ batch_size = MAX_GPU_BATCH_SIZE
+
+ set_seed(seed)
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size)
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", return_dict=True)
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+ # Instantiate optimizer
+ optimizer = AdamW(params=model.parameters(), lr=lr)
+
+ # Instantiate scheduler
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=100,
+ num_training_steps=(len(train_dataloader) * num_epochs) // gradient_accumulation_steps,
+ )
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # Now we train the model
+ for epoch in range(num_epochs):
+ model.train()
+ for step, batch in enumerate(train_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss = loss / gradient_accumulation_steps
+ accelerator.backward(loss)
+ if step % gradient_accumulation_steps == 0:
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # New code
+ # Check if we should stop the training on any processes
+ if callback.check_early_stopping(loss.item()):
+ accelerator.set_trigger()
+
+ # If so, we break the loop
+ if accelerator.check_trigger():
+ break
+
+ model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": 3, "seed": 42, "batch_size": 16}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/fsdp_with_peak_mem_tracking.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/fsdp_with_peak_mem_tracking.py
new file mode 100644
index 0000000000000000000000000000000000000000..0cd3fec55d5a4ea77c16168329a3d29f769fe1ed
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/fsdp_with_peak_mem_tracking.py
@@ -0,0 +1,458 @@
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import gc
+import os
+import threading
+
+import evaluate
+import psutil
+import torch
+from datasets import load_dataset
+from torch.distributed.fsdp.fully_sharded_data_parallel import FullOptimStateDictConfig, FullStateDictConfig
+from torch.utils.data import DataLoader
+from transformers import (
+ AutoModelForSequenceClassification,
+ AutoTokenizer,
+ get_linear_schedule_with_warmup,
+ set_seed,
+)
+
+from accelerate import Accelerator, DistributedType, FullyShardedDataParallelPlugin
+from accelerate.utils import is_npu_available, is_xpu_available
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate
+#
+# This example trains a Bert base model on GLUE MRPC
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+# - FSDP
+#
+# This example also demonstrates the checkpointing and sharding capabilities
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+
+# New Code #
+# Converting Bytes to Megabytes
+def b2mb(x):
+ return int(x / 2**20)
+
+
+# New Code #
+# This context manager is used to track the peak memory usage of the process
+class TorchTracemalloc:
+ def __enter__(self):
+ gc.collect()
+ if torch.cuda.is_available():
+ torch.cuda.empty_cache()
+ torch.cuda.reset_max_memory_allocated() # reset the peak gauge to zero
+ self.begin = torch.cuda.memory_allocated()
+ elif is_xpu_available():
+ torch.xpu.empty_cache()
+ torch.xpu.reset_max_memory_allocated() # reset the peak gauge to zero
+ self.begin = torch.xpu.memory_allocated()
+ elif is_npu_available():
+ torch.npu.empty_cache()
+ torch.npu.reset_max_memory_allocated() # reset the peak gauge to zero
+ self.begin = torch.npu.memory_allocated()
+ self.process = psutil.Process()
+
+ self.cpu_begin = self.cpu_mem_used()
+ self.peak_monitoring = True
+ peak_monitor_thread = threading.Thread(target=self.peak_monitor_func)
+ peak_monitor_thread.daemon = True
+ peak_monitor_thread.start()
+ return self
+
+ def cpu_mem_used(self):
+ """get resident set size memory for the current process"""
+ return self.process.memory_info().rss
+
+ def peak_monitor_func(self):
+ self.cpu_peak = -1
+
+ while True:
+ self.cpu_peak = max(self.cpu_mem_used(), self.cpu_peak)
+
+ # can't sleep or will not catch the peak right (this comment is here on purpose)
+ # time.sleep(0.001) # 1msec
+
+ if not self.peak_monitoring:
+ break
+
+ def __exit__(self, *exc):
+ self.peak_monitoring = False
+
+ gc.collect()
+ if torch.cuda.is_available():
+ torch.cuda.empty_cache()
+ self.end = torch.cuda.memory_allocated()
+ self.peak = torch.cuda.max_memory_allocated()
+ elif is_xpu_available():
+ torch.xpu.empty_cache()
+ self.end = torch.xpu.memory_allocated()
+ self.peak = torch.xpu.max_memory_allocated()
+ elif is_npu_available():
+ torch.npu.empty_cache()
+ self.end = torch.npu.memory_allocated()
+ self.peak = torch.npu.max_memory_allocated()
+ self.used = b2mb(self.end - self.begin)
+ self.peaked = b2mb(self.peak - self.begin)
+
+ self.cpu_end = self.cpu_mem_used()
+ self.cpu_used = b2mb(self.cpu_end - self.cpu_begin)
+ self.cpu_peaked = b2mb(self.cpu_peak - self.cpu_begin)
+ # print(f"delta used/peak {self.used:4d}/{self.peaked:4d}")
+
+
+# For testing only
+if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ from accelerate.test_utils.training import mocked_dataloaders
+
+ get_dataloaders = mocked_dataloaders # noqa: F811
+
+
+def training_function(config, args):
+ # For testing only
+ if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ config["num_epochs"] = 2
+
+ # New Code #
+ # Pass the advanced FSDP settings not part of the accelerate config by creating fsdp_plugin
+ fsdp_plugin = FullyShardedDataParallelPlugin(
+ state_dict_config=FullStateDictConfig(offload_to_cpu=False, rank0_only=False),
+ optim_state_dict_config=FullOptimStateDictConfig(offload_to_cpu=False, rank0_only=False),
+ )
+
+ # Initialize accelerator
+ if args.with_tracking:
+ accelerator = Accelerator(
+ cpu=args.cpu,
+ mixed_precision=args.mixed_precision,
+ log_with="wandb",
+ project_dir=args.logging_dir,
+ fsdp_plugin=fsdp_plugin,
+ )
+ else:
+ accelerator = Accelerator(fsdp_plugin=fsdp_plugin)
+ accelerator.print(accelerator.distributed_type)
+
+ if hasattr(args.checkpointing_steps, "isdigit"):
+ if args.checkpointing_steps == "epoch":
+ checkpointing_steps = args.checkpointing_steps
+ elif args.checkpointing_steps.isdigit():
+ checkpointing_steps = int(args.checkpointing_steps)
+ else:
+ raise ValueError(
+ f"Argument `checkpointing_steps` must be either a number or `epoch`. `{args.checkpointing_steps}` passed."
+ )
+ else:
+ checkpointing_steps = None
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+
+ # We need to initialize the trackers we use, and also store our configuration
+ if args.with_tracking:
+ experiment_config = vars(args)
+ accelerator.init_trackers("fsdp_glue_no_trainer", experiment_config)
+
+ tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
+ datasets = load_dataset("glue", "mrpc")
+ metric = evaluate.load("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ # If the batch size is too big we use gradient accumulation
+ gradient_accumulation_steps = 1
+ if batch_size > MAX_GPU_BATCH_SIZE and accelerator.distributed_type != DistributedType.XLA:
+ gradient_accumulation_steps = batch_size // MAX_GPU_BATCH_SIZE
+ batch_size = MAX_GPU_BATCH_SIZE
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ max_length = 128 if accelerator.distributed_type == DistributedType.XLA else None
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ set_seed(seed)
+
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained(
+ args.model_name_or_path, return_dict=True, low_cpu_mem_usage=True
+ )
+
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": 0.003,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+
+ optimizer = torch.optim.AdamW(params=optimizer_grouped_parameters, lr=lr, weight_decay=2e-4)
+
+ # Instantiate scheduler
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=10,
+ num_training_steps=(len(train_dataloader) * num_epochs) // gradient_accumulation_steps,
+ )
+
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ overall_step = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ accelerator.print(f"Resumed from checkpoint: {args.resume_from_checkpoint}")
+ accelerator.load_state(args.resume_from_checkpoint)
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ num_epochs -= int(training_difference.replace("epoch_", ""))
+ resume_step = None
+ else:
+ resume_step = int(training_difference.replace("step_", ""))
+ num_epochs -= resume_step // len(train_dataloader)
+ # If resuming by step, we also need to know exactly how far into the DataLoader we went
+ resume_step = (num_epochs * len(train_dataloader)) - resume_step
+
+ # Now we train the model
+ for epoch in range(num_epochs):
+ # New Code #
+ # context manager to track the peak memory usage during the training epoch
+ with TorchTracemalloc() as tracemalloc:
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ for step, batch in enumerate(train_dataloader):
+ # We need to skip steps until we reach the resumed step
+ if args.resume_from_checkpoint and epoch == 0:
+ if resume_step is not None and step < resume_step:
+ pass
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ accelerator.backward(loss)
+ if step % gradient_accumulation_steps == 0:
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ # accelerator.print(lr_scheduler.get_lr())
+
+ overall_step += 1
+
+ if isinstance(checkpointing_steps, int):
+ output_dir = f"step_{overall_step}"
+ if overall_step % checkpointing_steps == 0:
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+ # New Code #
+ # Printing the GPU memory usage details such as allocated memory, peak memory, and total memory usage
+ accelerator.print(f"Memory before entering the train : {b2mb(tracemalloc.begin)}")
+ accelerator.print(f"Memory consumed at the end of the train (end-begin): {tracemalloc.used}")
+ accelerator.print(f"Peak Memory consumed during the train (max-begin): {tracemalloc.peaked}")
+ accelerator.print(
+ f"Total Peak Memory consumed during the train (max): {tracemalloc.peaked + b2mb(tracemalloc.begin)}"
+ )
+ # Logging the peak memory usage of the GPU to the tracker
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "train_total_peak_memory": tracemalloc.peaked + b2mb(tracemalloc.begin),
+ },
+ step=epoch,
+ )
+
+ # New Code #
+ # context manager to track the peak memory usage during the evaluation
+ with TorchTracemalloc() as tracemalloc:
+ model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "accuracy": eval_metric["accuracy"],
+ "f1": eval_metric["f1"],
+ "train_loss": total_loss.item() / len(train_dataloader),
+ },
+ step=epoch,
+ )
+
+ if checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+ # New Code #
+ # Printing the GPU memory usage details such as allocated memory, peak memory, and total memory usage
+ accelerator.print(f"Memory before entering the eval : {b2mb(tracemalloc.begin)}")
+ accelerator.print(f"Memory consumed at the end of the eval (end-begin): {tracemalloc.used}")
+ accelerator.print(f"Peak Memory consumed during the eval (max-begin): {tracemalloc.peaked}")
+ accelerator.print(
+ f"Total Peak Memory consumed during the eval (max): {tracemalloc.peaked + b2mb(tracemalloc.begin)}"
+ )
+ # Logging the peak memory usage of the GPU to the tracker
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "eval_total_peak_memory": tracemalloc.peaked + b2mb(tracemalloc.begin),
+ },
+ step=epoch,
+ )
+
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to load in all available experiment trackers from the environment and use them for logging.",
+ )
+ parser.add_argument(
+ "--output_dir",
+ type=str,
+ default=".",
+ help="Optional save directory where all checkpoint folders will be stored. Default is the current working directory.",
+ )
+ parser.add_argument(
+ "--logging_dir",
+ type=str,
+ default="logs",
+ help="Location on where to store experiment tracking logs`",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=True,
+ )
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": 3, "seed": 42, "batch_size": 16}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/gradient_accumulation.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/gradient_accumulation.py
new file mode 100644
index 0000000000000000000000000000000000000000..d277bd7d8bb7345a5024e044655ed2569ff6f174
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/gradient_accumulation.py
@@ -0,0 +1,228 @@
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import os
+
+import evaluate
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup, set_seed
+
+from accelerate import Accelerator, DistributedType
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate
+# and perform gradient accumulation
+#
+# This example trains a Bert base model on GLUE MRPC
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+
+def get_dataloaders(accelerator: Accelerator, batch_size: int = 16):
+ """
+ Creates a set of `DataLoader`s for the `glue` dataset,
+ using "bert-base-cased" as the tokenizer.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ """
+ tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ max_length = 128 if accelerator.distributed_type == DistributedType.XLA else None
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+# For testing only
+if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ from accelerate.test_utils.training import mocked_dataloaders
+
+ get_dataloaders = mocked_dataloaders # noqa: F811
+
+
+def training_function(config, args):
+ # For testing only
+ if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ config["num_epochs"] = 2
+ # New Code #
+ gradient_accumulation_steps = int(args.gradient_accumulation_steps)
+ # Initialize accelerator
+ accelerator = Accelerator(
+ cpu=args.cpu, mixed_precision=args.mixed_precision, gradient_accumulation_steps=gradient_accumulation_steps
+ )
+ if accelerator.distributed_type == DistributedType.XLA and gradient_accumulation_steps > 1:
+ raise NotImplementedError(
+ "Gradient accumulation on TPUs is currently not supported. Pass `gradient_accumulation_steps=1`"
+ )
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+
+ metric = evaluate.load("glue", "mrpc")
+
+ set_seed(seed)
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size)
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", return_dict=True)
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+
+ # Instantiate optimizer
+ optimizer = AdamW(params=model.parameters(), lr=lr)
+
+ # Instantiate scheduler
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=100,
+ num_training_steps=(len(train_dataloader) * num_epochs),
+ )
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # Now we train the model
+ for epoch in range(num_epochs):
+ model.train()
+ for step, batch in enumerate(train_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ # New code #
+ # We use the new `accumulate` context manager to perform gradient accumulation
+ # We also currently do not support TPUs nor advise it as bugs were found on the XLA side when running our tests.
+ with accelerator.accumulate(model):
+ output = model(**batch)
+ loss = output.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+ # New Code #
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="The number of minibatches to be ran before gradients are accumulated.",
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": 3, "seed": 42, "batch_size": 16}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/gradient_accumulation_for_autoregressive_models.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/gradient_accumulation_for_autoregressive_models.py
new file mode 100644
index 0000000000000000000000000000000000000000..f21199bea8fc9d6269d948848085db322bebd15d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/gradient_accumulation_for_autoregressive_models.py
@@ -0,0 +1,341 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import contextlib
+import math
+import os
+
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForCausalLM, AutoTokenizer, get_constant_schedule, set_seed
+
+from accelerate import Accelerator, DistributedType
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate
+# and perform gradient accumulation on samples of variable size
+#
+# This example trains a SmolLM base model on WikiText-2 v1
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+
+EVAL_BATCH_SIZE = 32
+
+
+def get_dataloaders(accelerator: Accelerator, batch_size: int = 16, max_training_samples=500):
+ """
+ Creates a set of `DataLoader`s for the `Salesforce/wikitext` dataset,
+ using "HuggingFaceTB/SmolLM-360M" as the tokenizer.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ """
+ tokenizer = AutoTokenizer.from_pretrained("HuggingFaceTB/SmolLM-360M")
+ tokenizer.pad_token = tokenizer.eos_token
+ with accelerator.local_main_process_first():
+ datasets = load_dataset("Salesforce/wikitext", "wikitext-2-v1")
+ datasets["train"] = datasets["train"].select(range(max_training_samples))
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["text"], truncation=True, max_length=None, return_attention_mask=False)
+ return outputs
+
+ # Filter out empty texts
+ with accelerator.main_process_first():
+ datasets = datasets.filter(
+ lambda x: len(x) > 0,
+ input_columns="text",
+ )
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["text"],
+ )
+
+ # Filter out empty samples
+ with accelerator.main_process_first():
+ tokenized_datasets = tokenized_datasets.filter(
+ lambda x: len(x) > 0,
+ input_columns="input_ids",
+ )
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ max_length = (
+ 128
+ if accelerator.distributed_type == DistributedType.XLA
+ else max([len(e["input_ids"]) for e in examples])
+ )
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ batch = tokenizer.pad(
+ examples,
+ padding="max_length",
+ max_length=max_length + 1,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ batch["labels"] = batch["input_ids"][:, 1:]
+ batch["input_ids"] = batch["input_ids"][:, :-1]
+
+ batch["labels"] = torch.where(batch["labels"] == tokenizer.pad_token_id, -100, batch["labels"])
+
+ return batch
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=False, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+# For testing only
+if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ from accelerate.test_utils.training import mocked_dataloaders_for_autoregressive_models
+
+ get_dataloaders = mocked_dataloaders_for_autoregressive_models # noqa: F811
+
+
+def training_function(config, args):
+ # For testing only
+ if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ config["num_epochs"] = 2
+
+ gradient_accumulation_steps = int(args.gradient_accumulation_steps)
+ # Initialize accelerator
+ if args.with_wandb_tracking:
+ accelerator = Accelerator(
+ cpu=args.cpu,
+ mixed_precision=args.mixed_precision,
+ gradient_accumulation_steps=gradient_accumulation_steps,
+ log_with="wandb",
+ )
+ else:
+ accelerator = Accelerator(
+ cpu=args.cpu, mixed_precision=args.mixed_precision, gradient_accumulation_steps=gradient_accumulation_steps
+ )
+ if accelerator.distributed_type == DistributedType.XLA and gradient_accumulation_steps > 1:
+ raise NotImplementedError(
+ "Gradient accumulation on TPUs is currently not supported. Pass `gradient_accumulation_steps=1`"
+ )
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+ max_grad_norm = config["max_grad_norm"]
+
+ # We need to initialize the trackers we use, and also store our configuration
+ if args.with_wandb_tracking:
+ run = os.path.split(__file__)[-1].split(".")[0]
+ run_name = f"{accelerator.num_processes}GPU-grad{gradient_accumulation_steps}-bs{batch_size}"
+ accelerator.init_trackers(
+ run,
+ config,
+ init_kwargs={"wandb": {"name": run_name}},
+ )
+
+ set_seed(seed)
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size)
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForCausalLM.from_pretrained("HuggingFaceTB/SmolLM-360M")
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+
+ # Instantiate optimizer
+ optimizer = AdamW(params=model.parameters(), lr=lr)
+
+ # Instantiate scheduler
+ lr_scheduler = get_constant_schedule(
+ optimizer=optimizer,
+ )
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ num_samples_in_epoch = len(train_dataloader)
+ remainder = num_samples_in_epoch % gradient_accumulation_steps
+ remainder = remainder if remainder != 0 else gradient_accumulation_steps
+ total_gradient_updates = math.ceil(num_samples_in_epoch / gradient_accumulation_steps)
+
+ total_batched_samples = 0
+ # Now we train the model
+ for epoch in range(num_epochs):
+ model.train()
+ training_iterator = iter(train_dataloader)
+ for update_step in range(total_gradient_updates):
+ # In order to correctly the total number of non-padded tokens on which we'll compute the cross-entropy loss
+ # we need to pre-load the full local batch - i.e the next per_device_batch_size * accumulation_steps samples
+ batch_samples = []
+ num_batches_in_step = (
+ gradient_accumulation_steps if update_step != (total_gradient_updates - 1) else remainder
+ )
+ for _ in range(num_batches_in_step):
+ batch_samples += [next(training_iterator)]
+ # get local num items in batch
+ local_num_items_in_batch = sum([(batch["labels"].ne(-100)).sum() for batch in batch_samples])
+
+ # to compute it correctly in a multi-device DDP training, we need to gather the total number of items in the full batch.
+ num_items_in_batch = accelerator.gather(local_num_items_in_batch).sum().item()
+ losses = []
+ for i, batch in enumerate(batch_samples):
+ # if we perform gradient accumulation in a multi-devices set-up, we want to avoid unecessary communications when accumulating
+ # cf: https://muellerzr.github.io/blog/gradient_accumulation.html
+ ctx = (
+ model.no_sync
+ if (i < len(batch_samples) - 1 and accelerator.num_processes > 1)
+ else contextlib.nullcontext
+ )
+ with ctx():
+ total_batched_samples += 1
+
+ outputs = model(**batch, use_cache=False, num_items_in_batch=num_items_in_batch)
+ loss = outputs.loss
+
+ # We multiply by num_processes because the DDP calculates the average gradient across all devices whereas dividing by num_items_in_batch already takes into account all devices
+ # Same reason for gradient_accumulation_steps, but this times it's Accelerate that calculate the average gradient across the accumulated steps
+ # Because the loss is already divided by `num_items_in_batch` in the `transformers` code, we don't need to do it again
+ loss = loss * gradient_accumulation_steps * accelerator.num_processes
+ accelerator.backward(loss)
+ losses.append(loss.detach())
+
+ # Sync gradients and perform optimization steps once every gradient_accumulation_steps
+ grad_norm = accelerator.clip_grad_norm_(model.parameters(), max_grad_norm)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ losses = accelerator.gather(sum(losses)).sum().item() / (
+ accelerator.num_processes * gradient_accumulation_steps
+ )
+
+ grad_norm = grad_norm.detach().item() if isinstance(grad_norm, torch.Tensor) else grad_norm
+ accelerator.print(
+ f"epoch {epoch} - update step {update_step}:: grad norm: {grad_norm} ::train loss: {losses}"
+ )
+ if args.with_wandb_tracking:
+ accelerator.log(
+ {
+ "train/grad_norm": grad_norm,
+ "train/epoch": epoch,
+ "train/loss": losses,
+ },
+ step=update_step + total_gradient_updates * epoch,
+ )
+ model.eval()
+ losses = []
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = model(**batch, use_cache=False)
+ eval_loss = outputs.loss
+ losses.append(accelerator.gather_for_metrics(loss.repeat(EVAL_BATCH_SIZE)))
+
+ losses = torch.cat(losses)
+ try:
+ eval_loss = torch.mean(losses)
+ perplexity = math.exp(eval_loss)
+ except OverflowError:
+ perplexity = float("inf")
+
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:: eval perplexity: {perplexity} eval_loss: {eval_loss}")
+ if args.with_wandb_tracking:
+ accelerator.log(
+ {
+ "eval/perplexity": perplexity,
+ "eval/loss": eval_loss,
+ "eval/epoch": epoch,
+ },
+ step=update_step + total_gradient_updates * epoch,
+ )
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="The number of minibatches to be ran before gradients are accumulated.",
+ )
+ parser.add_argument(
+ "--per_device_batch_size",
+ type=int,
+ default=2,
+ help="The size of each minibatch",
+ )
+
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ parser.add_argument(
+ "--with_wandb_tracking",
+ action="store_true",
+ help="Whether to load in wandb from the environment and use them for logging.",
+ )
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": 3, "seed": 42, "batch_size": args.per_device_batch_size, "max_grad_norm": 1.0}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/local_sgd.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/local_sgd.py
new file mode 100644
index 0000000000000000000000000000000000000000..cdcf950af190fa71b403836f1a7ec2f0d6a8e3ec
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/local_sgd.py
@@ -0,0 +1,236 @@
+# Copyright 2023 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import os
+
+import evaluate
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup, set_seed
+
+from accelerate import Accelerator, DistributedType
+from accelerate.local_sgd import LocalSGD
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate
+# with LocalSGD, which is a method to synchronize model
+# parameters every K batches. It is different, but complementary
+# to gradient accumulation.
+#
+# This example trains a Bert base model on GLUE MRPC
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+
+def get_dataloaders(accelerator: Accelerator, batch_size: int = 16):
+ """
+ Creates a set of `DataLoader`s for the `glue` dataset,
+ using "bert-base-cased" as the tokenizer.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ """
+ tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ max_length = 128 if accelerator.distributed_type == DistributedType.XLA else None
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+# For testing only
+if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ from accelerate.test_utils.training import mocked_dataloaders
+
+ get_dataloaders = mocked_dataloaders # noqa: F811
+
+
+def training_function(config, args):
+ # For testing only
+ if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ config["num_epochs"] = 2
+ # New Code #
+ gradient_accumulation_steps = int(args.gradient_accumulation_steps)
+ local_sgd_steps = int(args.local_sgd_steps)
+ # Initialize accelerator
+ accelerator = Accelerator(
+ cpu=args.cpu, mixed_precision=args.mixed_precision, gradient_accumulation_steps=gradient_accumulation_steps
+ )
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+
+ metric = evaluate.load("glue", "mrpc")
+
+ set_seed(seed)
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size)
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", return_dict=True)
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+
+ # Instantiate optimizer
+ optimizer = AdamW(params=model.parameters(), lr=lr)
+
+ # Instantiate scheduler
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=100,
+ num_training_steps=(len(train_dataloader) * num_epochs),
+ )
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # Now we train the model
+ for epoch in range(num_epochs):
+ model.train()
+ with LocalSGD(
+ accelerator=accelerator, model=model, local_sgd_steps=local_sgd_steps, enabled=local_sgd_steps is not None
+ ) as local_sgd:
+ for step, batch in enumerate(train_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ # New code #
+ # We use the new `accumulate` context manager to perform gradient accumulation
+ # We also currently do not support TPUs nor advise it as bugs were found on the XLA side when running our tests.
+ with accelerator.accumulate(model):
+ output = model(**batch)
+ loss = output.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ # LocalSGD-specific line
+ local_sgd.step()
+
+ model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+ # New Code #
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="The number of minibatches to be ran before gradients are accumulated.",
+ )
+ parser.add_argument(
+ "--local_sgd_steps", type=int, default=8, help="Number of local SGD steps or None to disable local SGD"
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": 3, "seed": 42, "batch_size": 16}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/megatron_lm_gpt_pretraining.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/megatron_lm_gpt_pretraining.py
new file mode 100644
index 0000000000000000000000000000000000000000..7c1153bc49db3f050c3a82fc76dad9646571d182
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/megatron_lm_gpt_pretraining.py
@@ -0,0 +1,710 @@
+#!/usr/bin/env python
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for causal language modeling (GPT, GPT-2, CTRL, ...)
+on a text file or a dataset without using HuggingFace Trainer.
+
+Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
+https://huggingface.co/models?filter=text-generation
+"""
+# You can also adapt this script on your own causal language modeling task. Pointers for this are left as comments.
+
+import argparse
+import json
+import logging
+import math
+import os
+import random
+from itertools import chain
+from pathlib import Path
+
+import datasets
+import torch
+import transformers
+from datasets import load_dataset
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from tqdm.auto import tqdm
+from transformers import (
+ CONFIG_MAPPING,
+ MODEL_MAPPING,
+ AutoConfig,
+ AutoModelForCausalLM,
+ AutoTokenizer,
+ SchedulerType,
+ default_data_collator,
+ get_scheduler,
+)
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+from accelerate import Accelerator, DistributedType
+from accelerate.logging import get_logger
+from accelerate.utils import MegatronLMDummyScheduler, set_seed
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.23.0.dev0")
+
+logger = get_logger(__name__)
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
+
+MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Finetune a transformers model on a causal language modeling task")
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ default=None,
+ help="The name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--dataset_config_name",
+ type=str,
+ default=None,
+ help="The configuration name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
+ )
+ parser.add_argument(
+ "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
+ )
+ parser.add_argument(
+ "--validation_split_percentage",
+ default=5,
+ help="The percentage of the train set used as validation set in case there's no validation split",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=False,
+ )
+ parser.add_argument(
+ "--config_name",
+ type=str,
+ default=None,
+ help="Pretrained config name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ type=str,
+ default=None,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--use_slow_tokenizer",
+ action="store_true",
+ help="If passed, will use a slow tokenizer (not backed by the 🤗 Tokenizers library).",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument(
+ "--model_type",
+ type=str,
+ default=None,
+ help="Model type to use if training from scratch.",
+ choices=MODEL_TYPES,
+ )
+ parser.add_argument(
+ "--block_size",
+ type=int,
+ default=None,
+ help=(
+ "Optional input sequence length after tokenization. The training dataset will be truncated in block of"
+ " this size for training. Default to the model max input length for single sentence inputs (take into"
+ " account special tokens)."
+ ),
+ )
+ parser.add_argument(
+ "--preprocessing_num_workers",
+ type=int,
+ default=None,
+ help="The number of processes to use for the preprocessing.",
+ )
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+ parser.add_argument(
+ "--no_keep_linebreaks", action="store_true", help="Do not keep line breaks when using TXT files."
+ )
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"`, and `"dvclive"`, and `"swanlab"`. Use `"all"` (default) to report to all integrations.'
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+ if args.dataset_name is None and args.train_file is None and args.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if args.train_file is not None:
+ extension = args.train_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, json or txt file."
+ if args.validation_file is not None:
+ extension = args.validation_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, json or txt file."
+
+ if args.push_to_hub:
+ assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
+
+ return args
+
+
+def main():
+ args = parse_args()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_clm_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+ accelerator_log_kwargs = {}
+
+ if args.with_tracking:
+ accelerator_log_kwargs["log_with"] = args.report_to
+ accelerator_log_kwargs["project_dir"] = args.output_dir
+
+ accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ api = HfApi(token=args.hub_token)
+
+ # Create repo (repo_name from args or inferred)
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ repo_id = api.create_repo(repo_name, exist_ok=True).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(args.dataset_name, args.dataset_config_name)
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ args.dataset_name,
+ args.dataset_config_name,
+ split=f"train[:{args.validation_split_percentage}%]",
+ )
+ raw_datasets["train"] = load_dataset(
+ args.dataset_name,
+ args.dataset_config_name,
+ split=f"train[{args.validation_split_percentage}%:]",
+ )
+ else:
+ data_files = {}
+ dataset_args = {}
+ if args.train_file is not None:
+ data_files["train"] = args.train_file
+ if args.validation_file is not None:
+ data_files["validation"] = args.validation_file
+ extension = args.train_file.split(".")[-1]
+ if extension == "txt":
+ extension = "text"
+ dataset_args["keep_linebreaks"] = not args.no_keep_linebreaks
+ raw_datasets = load_dataset(extension, data_files=data_files, **dataset_args)
+ # If no validation data is there, validation_split_percentage will be used to divide the dataset.
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[:{args.validation_split_percentage}%]",
+ **dataset_args,
+ )
+ raw_datasets["train"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[{args.validation_split_percentage}%:]",
+ **dataset_args,
+ )
+
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.html.
+
+ # Load pretrained model and tokenizer
+ #
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ if args.config_name:
+ config = AutoConfig.from_pretrained(args.config_name)
+ elif args.model_name_or_path:
+ config = AutoConfig.from_pretrained(args.model_name_or_path)
+ else:
+ config = CONFIG_MAPPING[args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ if args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(args.tokenizer_name, use_fast=not args.use_slow_tokenizer)
+ elif args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path, use_fast=not args.use_slow_tokenizer)
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script."
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if args.model_name_or_path:
+ model = AutoModelForCausalLM.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = AutoModelForCausalLM.from_config(config)
+
+ model.resize_token_embeddings(len(tokenizer))
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ column_names = raw_datasets["train"].column_names
+ text_column_name = "text" if "text" in column_names else column_names[0]
+
+ def tokenize_function(examples):
+ return tokenizer(examples[text_column_name])
+
+ with accelerator.main_process_first():
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Running tokenizer on dataset",
+ )
+
+ if args.block_size is None:
+ block_size = tokenizer.model_max_length
+ if block_size > 1024:
+ logger.warning(
+ f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
+ "Picking 1024 instead. You can change that default value by passing --block_size xxx."
+ )
+ block_size = 1024
+ else:
+ if args.block_size > tokenizer.model_max_length:
+ logger.warning(
+ f"The block_size passed ({args.block_size}) is larger than the maximum length for the model"
+ f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
+ )
+ block_size = min(args.block_size, tokenizer.model_max_length)
+
+ # Main data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
+ def group_texts(examples):
+ # Concatenate all texts.
+ concatenated_examples = {k: list(chain(*examples[k])) for k in examples.keys()}
+ total_length = len(concatenated_examples[list(examples.keys())[0]])
+ # We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
+ # customize this part to your needs.
+ if total_length >= block_size:
+ total_length = (total_length // block_size) * block_size
+ # Split by chunks of max_len.
+ result = {
+ k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
+ for k, t in concatenated_examples.items()
+ }
+ result["labels"] = result["input_ids"].copy()
+ return result
+
+ # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
+ # for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
+ # to preprocess.
+ #
+ # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
+ # https://huggingface.co/docs/datasets/package_reference/main_classes.html#datasets.Dataset.map
+
+ with accelerator.main_process_first():
+ lm_datasets = tokenized_datasets.map(
+ group_texts,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ load_from_cache_file=not args.overwrite_cache,
+ desc=f"Grouping texts in chunks of {block_size}",
+ )
+
+ train_dataset = lm_datasets["train"]
+ eval_dataset = lm_datasets["validation"]
+
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ # DataLoaders creation:
+ train_dataloader = DataLoader(
+ train_dataset, shuffle=True, collate_fn=default_data_collator, batch_size=args.per_device_train_batch_size
+ )
+ eval_dataloader = DataLoader(
+ eval_dataset, collate_fn=default_data_collator, batch_size=args.per_device_eval_batch_size
+ )
+
+ # Optimizer
+ # Split weights in two groups, one with weight decay and the other not.
+ no_decay = ["bias", "layer_norm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ # New Code
+ # For Megatron-LM, we need to use `MegatronLMDummyScheduler` instead of regular schedulers
+ if accelerator.distributed_type == DistributedType.MEGATRON_LM:
+ lr_scheduler = MegatronLMDummyScheduler(
+ optimizer=optimizer,
+ total_num_steps=args.max_train_steps,
+ warmup_num_steps=args.num_warmup_steps,
+ )
+ else:
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps * args.gradient_accumulation_steps,
+ num_training_steps=args.max_train_steps * args.gradient_accumulation_steps,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # On TPU, the tie weights in our model have been disconnected, so we need to restore the ties.
+ if accelerator.distributed_type == DistributedType.XLA:
+ model.tie_weights()
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("clm_no_trainer", experiment_config)
+
+ # Train!
+ # New Code
+ # For Megatron-LM, we need to get `global_batch_size` from megatron_lm_plugin
+ # as it handles the specifics related to data parallelism, tensor model parallelism and pipeline parallelism
+ if accelerator.distributed_type == DistributedType.MEGATRON_LM:
+ total_batch_size = accelerator.state.megatron_lm_plugin.global_batch_size
+ else:
+ total_batch_size = (
+ args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+ )
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ accelerator.print(f"Resumed from checkpoint: {args.resume_from_checkpoint}")
+ accelerator.load_state(args.resume_from_checkpoint)
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(starting_epoch * num_update_steps_per_epoch)
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ for step, batch in enumerate(train_dataloader):
+ # We need to skip steps until we reach the resumed step
+ if args.resume_from_checkpoint and epoch == starting_epoch:
+ if resume_step is not None and step < resume_step:
+ if step % args.gradient_accumulation_steps == 0:
+ progress_bar.update(1)
+ completed_steps += 1
+ continue
+
+ with accelerator.accumulate(model):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # Checks if the accelerator has performed an optimization step behind the scenes
+ if accelerator.sync_gradients:
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+ if completed_steps >= args.max_train_steps:
+ break
+
+ model.eval()
+ losses = []
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+
+ loss = outputs.loss
+ # New Code
+ # For Megatron-LM, the losses are already averaged across the data parallel group
+ if accelerator.distributed_type == DistributedType.MEGATRON_LM:
+ losses.append(loss)
+ else:
+ losses.append(accelerator.gather_for_metrics(loss.repeat(args.per_device_eval_batch_size)))
+ try:
+ if accelerator.distributed_type == DistributedType.MEGATRON_LM:
+ losses = torch.tensor(losses)
+ else:
+ losses = torch.cat(losses)
+ eval_loss = torch.mean(losses)
+ perplexity = math.exp(eval_loss)
+ except OverflowError:
+ perplexity = float("inf")
+
+ logger.info(f"epoch {epoch}: perplexity: {perplexity} eval_loss: {eval_loss}")
+
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "perplexity": perplexity,
+ "eval_loss": eval_loss,
+ "train_loss": total_loss.item() / len(train_dataloader),
+ "epoch": epoch,
+ "step": completed_steps,
+ },
+ step=completed_steps,
+ )
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ api.upload_folder(
+ repo_id=repo_id,
+ folder_path=args.output_dir,
+ commit_message=f"Training in progress epoch {epoch}",
+ run_as_future=True,
+ )
+
+ if args.checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ # this is causing some issue with Megatron-LM when using `wandb` at the end of the main function.
+ # Everything works fine inspite of commenting this out. (wandb finishes/closes the run without error)
+ # if args.with_tracking:
+ # accelerator.end_training()
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ # New Code
+ # For Megatron-LM, we need to save the model using `accelerator.save_state`
+ if accelerator.distributed_type == DistributedType.MEGATRON_LM:
+ accelerator.save_state(args.output_dir)
+ else:
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ if args.push_to_hub:
+ api.upload_folder(
+ repo_id=repo_id,
+ folder_path=args.output_dir,
+ commit_message="End of training",
+ )
+
+ with open(os.path.join(args.output_dir, "all_results.json"), "w") as f:
+ json.dump({"perplexity": perplexity}, f)
+ accelerator.end_training()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/memory.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/memory.py
new file mode 100644
index 0000000000000000000000000000000000000000..847135e426eed5f87d5bc853cc80a98c255a3984
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/memory.py
@@ -0,0 +1,234 @@
+# Copyright 2022 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import os
+
+# New Code #
+import evaluate
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup, set_seed
+
+from accelerate import Accelerator, DistributedType
+from accelerate.utils import find_executable_batch_size
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate,
+# specifically showcasing how to ensure out-of-memory errors never
+# interrupt training, and builds off the `nlp_example.py` script.
+#
+# This example trains a Bert base model on GLUE MRPC
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# New additions from the base script can be found quickly by
+# looking for the # New Code # tags
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+
+def get_dataloaders(accelerator: Accelerator, batch_size: int = 16):
+ """
+ Creates a set of `DataLoader`s for the `glue` dataset,
+ using "bert-base-cased" as the tokenizer.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ """
+ tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ max_length = 128 if accelerator.distributed_type == DistributedType.XLA else None
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+# For testing only
+if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ from accelerate.test_utils.training import mocked_dataloaders
+
+ get_dataloaders = mocked_dataloaders # noqa: F811
+
+
+def training_function(config, args):
+ # For testing only
+ if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ config["num_epochs"] = 2
+ # Initialize accelerator
+ accelerator = Accelerator(cpu=args.cpu, mixed_precision=args.mixed_precision)
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+
+ metric = evaluate.load("glue", "mrpc")
+
+ # New Code #
+ # We now can define an inner training loop function. It should take a batch size as the only parameter,
+ # and build the dataloaders in there.
+ # It also gets our decorator
+ @find_executable_batch_size(starting_batch_size=batch_size)
+ def inner_training_loop(batch_size):
+ # And now just move everything below under this function
+ # We need to bring in the Accelerator object from earlier
+ nonlocal accelerator
+ # And reset all of its attributes that could hold onto any memory:
+ accelerator.free_memory()
+
+ # Then we can declare the model, optimizer, and everything else:
+ set_seed(seed)
+
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", return_dict=True)
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+
+ # Instantiate optimizer
+ optimizer = AdamW(params=model.parameters(), lr=lr)
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size)
+
+ # Instantiate scheduler
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=100,
+ num_training_steps=(len(train_dataloader) * num_epochs),
+ )
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # Now we train the model
+ for epoch in range(num_epochs):
+ model.train()
+ for step, batch in enumerate(train_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ outputs = model(**batch)
+ loss = outputs.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+
+ # New Code #
+ # And call it at the end with no arguments
+ # Note: You could also refactor this outside of your training loop function
+ inner_training_loop()
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": 3, "seed": 42, "batch_size": 16}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/multi_process_metrics.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/multi_process_metrics.py
new file mode 100644
index 0000000000000000000000000000000000000000..626781ac81184ffe42ed9d2f7fd952fe1207a4f7
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/multi_process_metrics.py
@@ -0,0 +1,238 @@
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import os
+
+import evaluate
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup, set_seed
+
+from accelerate import Accelerator, DistributedType
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate,
+# specifically showcasing how to properly calculate the metrics on the
+# validation dataset when in a distributed system, and builds off the
+# `nlp_example.py` script.
+#
+# This example trains a Bert base model on GLUE MRPC
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# To help focus on the differences in the code, building `DataLoaders`
+# was refactored into its own function.
+# New additions from the base script can be found quickly by
+# looking for the # New Code # tags
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+
+def get_dataloaders(accelerator: Accelerator, batch_size: int = 16):
+ """
+ Creates a set of `DataLoader`s for the `glue` dataset,
+ using "bert-base-cased" as the tokenizer.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ """
+ tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ max_length = 128 if accelerator.distributed_type == DistributedType.XLA else None
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+# For testing only
+if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ from accelerate.test_utils.training import mocked_dataloaders
+
+ get_dataloaders = mocked_dataloaders # noqa: F811
+
+
+def training_function(config, args):
+ # For testing only
+ if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ config["num_epochs"] = 2
+ # Initialize accelerator
+ accelerator = Accelerator(cpu=args.cpu, mixed_precision=args.mixed_precision)
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+
+ metric = evaluate.load("glue", "mrpc")
+
+ # If the batch size is too big we use gradient accumulation
+ gradient_accumulation_steps = 1
+ if batch_size > MAX_GPU_BATCH_SIZE and accelerator.distributed_type != DistributedType.XLA:
+ gradient_accumulation_steps = batch_size // MAX_GPU_BATCH_SIZE
+ batch_size = MAX_GPU_BATCH_SIZE
+
+ set_seed(seed)
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size)
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", return_dict=True)
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+
+ # Instantiate optimizer
+ optimizer = AdamW(params=model.parameters(), lr=lr)
+
+ # Instantiate scheduler
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=100,
+ num_training_steps=(len(train_dataloader) * num_epochs) // gradient_accumulation_steps,
+ )
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # Now we train the model
+ for epoch in range(num_epochs):
+ model.train()
+ for step, batch in enumerate(train_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss = loss / gradient_accumulation_steps
+ accelerator.backward(loss)
+ if step % gradient_accumulation_steps == 0:
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ model.eval()
+ samples_seen = 0
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather((predictions, batch["labels"]))
+ # New Code #
+ # First we check if it's a distributed system
+ if accelerator.use_distributed:
+ # Then see if we're on the last batch of our eval dataloader
+ if step == len(eval_dataloader) - 1:
+ # Last batch needs to be truncated on distributed systems as it contains additional samples
+ predictions = predictions[: len(eval_dataloader.dataset) - samples_seen]
+ references = references[: len(eval_dataloader.dataset) - samples_seen]
+ else:
+ # Otherwise we add the number of samples seen
+ samples_seen += references.shape[0]
+ # All of this can be avoided if you use `Accelerator.gather_for_metrics` instead of `Accelerator.gather`:
+ # accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": 3, "seed": 42, "batch_size": 16}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/profiler.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/profiler.py
new file mode 100644
index 0000000000000000000000000000000000000000..bb315cf6ca576c06b15fb819db4a8ac2fd7c8d2c
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/profiler.py
@@ -0,0 +1,256 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import os
+
+import evaluate
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup, set_seed
+
+from accelerate import Accelerator, DistributedType
+from accelerate.utils import ProfileKwargs
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate
+# and perform profiling
+#
+# This example trains a Bert base model on GLUE MRPC
+# in any of the following settings (with the same script):
+# - single CPU or single device (CUDA GPU, Intel XPU etc.)
+# - multi devices (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+
+def get_dataloaders(accelerator: Accelerator, batch_size: int = 16):
+ """
+ Creates a set of `DataLoader`s for the `glue` dataset,
+ using "bert-base-cased" as the tokenizer.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ """
+ tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ max_length = 128 if accelerator.distributed_type == DistributedType.XLA else None
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+# For testing only
+if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ from accelerate.test_utils.training import mocked_dataloaders
+
+ get_dataloaders = mocked_dataloaders # noqa: F811
+
+
+def training_function(config, args):
+ # For testing only
+ if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ config["num_epochs"] = 2
+ # New Code #
+ profile_kwargs = ProfileKwargs(
+ record_shapes=args.record_shapes,
+ profile_memory=args.profile_memory,
+ with_flops=args.with_flops,
+ output_trace_dir=args.output_trace_dir,
+ )
+ # Initialize accelerator
+ accelerator = Accelerator(cpu=args.cpu, mixed_precision=args.mixed_precision, kwargs_handlers=[profile_kwargs])
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+
+ metric = evaluate.load("glue", "mrpc")
+
+ set_seed(seed)
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size)
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", return_dict=True)
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+
+ # Instantiate optimizer
+ optimizer = AdamW(params=model.parameters(), lr=lr)
+
+ # Instantiate scheduler
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=100,
+ num_training_steps=(len(train_dataloader) * num_epochs),
+ )
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # Now we train the model
+ for epoch in range(num_epochs):
+ model.train()
+ # New Code #
+ with accelerator.profile() as prof:
+ for step, batch in enumerate(train_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ # We use the new `accumulate` context manager to perform gradient accumulation
+ with accelerator.accumulate(model):
+ output = model(**batch)
+ loss = output.loss
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ # New Code #
+ accelerator.print(
+ prof.key_averages().table(
+ sort_by="self_cpu_time_total" if args.cpu else f"self_{accelerator.device.type}_time_total",
+ row_limit=-1,
+ )
+ )
+
+ model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU or an Intel XPU.",
+ )
+ # New Code #
+ parser.add_argument(
+ "--record_shapes",
+ action="store_true",
+ default=False,
+ help="If passed, will record shapes for profiling.",
+ )
+ # New Code #
+ parser.add_argument(
+ "--profile_memory",
+ action="store_true",
+ default=False,
+ help="If passed, will profile memory.",
+ )
+ # New Code #
+ parser.add_argument(
+ "--with_flops",
+ action="store_true",
+ default=False,
+ help="If passed, will profile flops.",
+ )
+ # New Code #
+ parser.add_argument(
+ "--output_trace_dir",
+ type=str,
+ default=None,
+ help="If passed, will save a json trace to the specified path.",
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": 3, "seed": 42, "batch_size": 16}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/schedule_free.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/schedule_free.py
new file mode 100644
index 0000000000000000000000000000000000000000..e9cf11702c8bd6b668ee40c307259099e3ca4f76
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/schedule_free.py
@@ -0,0 +1,226 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import os
+
+import evaluate
+import torch
+from datasets import load_dataset
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, set_seed
+
+from accelerate import Accelerator, DistributedType
+from accelerate.utils import is_schedulefree_available
+
+
+if is_schedulefree_available():
+ import schedulefree
+else:
+ raise ImportError(
+ "This example requires the `schedulefree` library. Please install it with `pip install schedulefree`"
+ )
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate and Facebook's
+# scheduler-free optimizer: https://github.com/facebookresearch/schedule_free/
+#
+# This example trains a Bert base model on GLUE MRPC
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+
+def get_dataloaders(accelerator: Accelerator, batch_size: int = 16):
+ """
+ Creates a set of `DataLoader`s for the `glue` dataset,
+ using "bert-base-cased" as the tokenizer.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ """
+ tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # For Torchxla, it's best to pad everything to the same length or training will be very slow.
+ max_length = 128 if accelerator.distributed_type == DistributedType.XLA else None
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size, drop_last=True
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"],
+ shuffle=False,
+ collate_fn=collate_fn,
+ batch_size=EVAL_BATCH_SIZE,
+ drop_last=(accelerator.mixed_precision == "fp8"),
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+# For testing only
+
+
+if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ from accelerate.test_utils.training import mocked_dataloaders
+
+ get_dataloaders = mocked_dataloaders # noqa: F811
+
+
+def training_function(config, args):
+ # Initialize accelerator
+ accelerator = Accelerator(cpu=args.cpu, mixed_precision=args.mixed_precision)
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+
+ metric = evaluate.load("glue", "mrpc")
+
+ # If the batch size is too big we use gradient accumulation
+ gradient_accumulation_steps = 1
+ if batch_size > MAX_GPU_BATCH_SIZE and accelerator.distributed_type != DistributedType.XLA:
+ gradient_accumulation_steps = batch_size // MAX_GPU_BATCH_SIZE
+ batch_size = MAX_GPU_BATCH_SIZE
+
+ set_seed(seed)
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size)
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", return_dict=True)
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+ # Instantiate optimizer with warmup steps
+ optimizer = schedulefree.AdamWScheduleFree(
+ model.parameters(),
+ lr=lr,
+ warmup_steps=100,
+ )
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+
+ model, optimizer, train_dataloader, eval_dataloader = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader
+ )
+
+ # Now we train the model
+ for epoch in range(num_epochs):
+ model.train()
+ optimizer.train()
+ for step, batch in enumerate(train_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss = loss / gradient_accumulation_steps
+ accelerator.backward(loss)
+ if step % gradient_accumulation_steps == 0:
+ optimizer.step()
+ optimizer.zero_grad()
+
+ model.eval()
+ optimizer.eval()
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": 3, "seed": 42, "batch_size": 16}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/tracking.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/tracking.py
new file mode 100644
index 0000000000000000000000000000000000000000..c97c5517b3527b994111d498cd4c81a30ec3e763
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/by_feature/tracking.py
@@ -0,0 +1,271 @@
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import os
+
+import evaluate
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup, set_seed
+
+from accelerate import Accelerator, DistributedType
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate,
+# specifically showcasing the experiment tracking capability,
+# and builds off the `nlp_example.py` script.
+#
+# This example trains a Bert base model on GLUE MRPC
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# To help focus on the differences in the code, building `DataLoaders`
+# was refactored into its own function.
+# New additions from the base script can be found quickly by
+# looking for the # New Code # tags
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+
+def get_dataloaders(accelerator: Accelerator, batch_size: int = 16):
+ """
+ Creates a set of `DataLoader`s for the `glue` dataset,
+ using "bert-base-cased" as the tokenizer.
+
+ Args:
+ accelerator (`Accelerator`):
+ An `Accelerator` object
+ batch_size (`int`, *optional*):
+ The batch size for the train and validation DataLoaders.
+ """
+ tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
+ datasets = load_dataset("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ max_length = 128 if accelerator.distributed_type == DistributedType.XLA else None
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ return train_dataloader, eval_dataloader
+
+
+# For testing only
+if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ from accelerate.test_utils.training import mocked_dataloaders
+
+ get_dataloaders = mocked_dataloaders # noqa: F811
+
+
+def training_function(config, args):
+ # For testing only
+ if os.environ.get("TESTING_MOCKED_DATALOADERS", None) == "1":
+ config["num_epochs"] = 2
+ # Initialize Accelerator
+
+ # New Code #
+ # We pass in "all" to `log_with` to grab all available trackers in the environment
+ # Note: If using a custom `Tracker` class, should be passed in here such as:
+ # >>> log_with = ["all", MyCustomTrackerClassInstance()]
+ if args.with_tracking:
+ accelerator = Accelerator(
+ cpu=args.cpu, mixed_precision=args.mixed_precision, log_with="all", project_dir=args.project_dir
+ )
+ else:
+ accelerator = Accelerator(cpu=args.cpu, mixed_precision=args.mixed_precision)
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+ set_seed(seed)
+
+ train_dataloader, eval_dataloader = get_dataloaders(accelerator, batch_size)
+ metric = evaluate.load("glue", "mrpc")
+
+ # If the batch size is too big we use gradient accumulation
+ gradient_accumulation_steps = 1
+ if batch_size > MAX_GPU_BATCH_SIZE and accelerator.distributed_type != DistributedType.XLA:
+ gradient_accumulation_steps = batch_size // MAX_GPU_BATCH_SIZE
+ batch_size = MAX_GPU_BATCH_SIZE
+
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", return_dict=True)
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+
+ # Instantiate optimizer
+ optimizer = AdamW(params=model.parameters(), lr=lr)
+
+ # Instantiate scheduler
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=100,
+ num_training_steps=(len(train_dataloader) * num_epochs) // gradient_accumulation_steps,
+ )
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # New Code #
+ # We need to initialize the trackers we use. Overall configurations can also be stored
+ if args.with_tracking:
+ run = os.path.split(__file__)[-1].split(".")[0]
+ accelerator.init_trackers(run, config)
+
+ # Now we train the model
+ for epoch in range(num_epochs):
+ model.train()
+ # New Code #
+ # For our tracking example, we will log the total loss of each epoch
+ if args.with_tracking:
+ total_loss = 0
+ for step, batch in enumerate(train_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ outputs = model(**batch)
+ loss = outputs.loss
+ # New Code #
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ loss = loss / gradient_accumulation_steps
+ accelerator.backward(loss)
+ if step % gradient_accumulation_steps == 0:
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True` (the default).
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+
+ # New Code #
+ # To actually log, we call `Accelerator.log`
+ # The values passed can be of `str`, `int`, `float` or `dict` of `str` to `float`/`int`
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "accuracy": eval_metric["accuracy"],
+ "f1": eval_metric["f1"],
+ "train_loss": total_loss.item() / len(train_dataloader),
+ "epoch": epoch,
+ },
+ step=epoch,
+ )
+
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to load in all available experiment trackers from the environment and use them for logging.",
+ )
+ parser.add_argument(
+ "--project_dir",
+ type=str,
+ default="logs",
+ help="Location on where to store experiment tracking logs` and relevent project information",
+ )
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": 3, "seed": 42, "batch_size": 16}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/complete_cv_example.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/complete_cv_example.py
new file mode 100644
index 0000000000000000000000000000000000000000..9fa9fceb853fb08ccc567fb6be434f69e95375ee
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/complete_cv_example.py
@@ -0,0 +1,329 @@
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import os
+import re
+
+import numpy as np
+import PIL
+import torch
+from timm import create_model
+from torch.optim.lr_scheduler import OneCycleLR
+from torch.utils.data import DataLoader, Dataset
+from torchvision.transforms import Compose, RandomResizedCrop, Resize, ToTensor
+
+from accelerate import Accelerator, DataLoaderConfiguration
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate
+#
+# This example trains a ResNet50 on the Oxford-IIT Pet Dataset
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+
+# Function to get the label from the filename
+def extract_label(fname):
+ stem = fname.split(os.path.sep)[-1]
+ return re.search(r"^(.*)_\d+\.jpg$", stem).groups()[0]
+
+
+class PetsDataset(Dataset):
+ def __init__(self, file_names, image_transform=None, label_to_id=None):
+ self.file_names = file_names
+ self.image_transform = image_transform
+ self.label_to_id = label_to_id
+
+ def __len__(self):
+ return len(self.file_names)
+
+ def __getitem__(self, idx):
+ fname = self.file_names[idx]
+ raw_image = PIL.Image.open(fname)
+ image = raw_image.convert("RGB")
+ if self.image_transform is not None:
+ image = self.image_transform(image)
+ label = extract_label(fname)
+ if self.label_to_id is not None:
+ label = self.label_to_id[label]
+ return {"image": image, "label": label}
+
+
+def training_function(config, args):
+ # Initialize accelerator
+ dataloader_config = DataLoaderConfiguration(use_stateful_dataloader=args.use_stateful_dataloader)
+ if args.with_tracking:
+ accelerator = Accelerator(
+ cpu=args.cpu,
+ mixed_precision=args.mixed_precision,
+ log_with="all",
+ project_dir=args.project_dir,
+ dataloader_config=dataloader_config,
+ )
+ else:
+ accelerator = Accelerator(
+ cpu=args.cpu, mixed_precision=args.mixed_precision, dataloader_config=dataloader_config
+ )
+
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+ image_size = config["image_size"]
+ if not isinstance(image_size, (list, tuple)):
+ image_size = (image_size, image_size)
+
+ # Parse out whether we are saving every epoch or after a certain number of batches
+ if hasattr(args.checkpointing_steps, "isdigit"):
+ if args.checkpointing_steps == "epoch":
+ checkpointing_steps = args.checkpointing_steps
+ elif args.checkpointing_steps.isdigit():
+ checkpointing_steps = int(args.checkpointing_steps)
+ else:
+ raise ValueError(
+ f"Argument `checkpointing_steps` must be either a number or `epoch`. `{args.checkpointing_steps}` passed."
+ )
+ else:
+ checkpointing_steps = None
+
+ # We need to initialize the trackers we use, and also store our configuration
+ if args.with_tracking:
+ run = os.path.split(__file__)[-1].split(".")[0]
+ accelerator.init_trackers(run, config)
+
+ # Grab all the image filenames
+ file_names = [os.path.join(args.data_dir, fname) for fname in os.listdir(args.data_dir) if fname.endswith(".jpg")]
+
+ # Build the label correspondences
+ all_labels = [extract_label(fname) for fname in file_names]
+ id_to_label = list(set(all_labels))
+ id_to_label.sort()
+ label_to_id = {lbl: i for i, lbl in enumerate(id_to_label)}
+
+ # Set the seed before splitting the data.
+ np.random.seed(seed)
+ torch.manual_seed(seed)
+ torch.cuda.manual_seed_all(seed)
+
+ # Split our filenames between train and validation
+ random_perm = np.random.permutation(len(file_names))
+ cut = int(0.8 * len(file_names))
+ train_split = random_perm[:cut]
+ eval_split = random_perm[cut:]
+
+ # For training we use a simple RandomResizedCrop
+ train_tfm = Compose([RandomResizedCrop(image_size, scale=(0.5, 1.0)), ToTensor()])
+ train_dataset = PetsDataset(
+ [file_names[i] for i in train_split], image_transform=train_tfm, label_to_id=label_to_id
+ )
+
+ # For evaluation, we use a deterministic Resize
+ eval_tfm = Compose([Resize(image_size), ToTensor()])
+ eval_dataset = PetsDataset([file_names[i] for i in eval_split], image_transform=eval_tfm, label_to_id=label_to_id)
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(train_dataset, shuffle=True, batch_size=batch_size, num_workers=4)
+ eval_dataloader = DataLoader(eval_dataset, shuffle=False, batch_size=batch_size, num_workers=4)
+
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = create_model("resnet50d", pretrained=True, num_classes=len(label_to_id))
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+
+ # Freezing the base model
+ for param in model.parameters():
+ param.requires_grad = False
+ for param in model.get_classifier().parameters():
+ param.requires_grad = True
+
+ # We normalize the batches of images to be a bit faster.
+ mean = torch.tensor(model.default_cfg["mean"])[None, :, None, None].to(accelerator.device)
+ std = torch.tensor(model.default_cfg["std"])[None, :, None, None].to(accelerator.device)
+
+ # Instantiate optimizer
+ optimizer = torch.optim.Adam(params=model.parameters(), lr=lr / 25)
+
+ # Instantiate learning rate scheduler
+ lr_scheduler = OneCycleLR(optimizer=optimizer, max_lr=lr, epochs=num_epochs, steps_per_epoch=len(train_dataloader))
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+ # We need to keep track of how many total steps we have iterated over
+ overall_step = 0
+ # We also need to keep track of the starting epoch so files are named properly
+ starting_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ accelerator.print(f"Resumed from checkpoint: {args.resume_from_checkpoint}")
+ accelerator.load_state(args.resume_from_checkpoint)
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ else:
+ resume_step = int(training_difference.replace("step_", ""))
+ starting_epoch = resume_step // len(train_dataloader)
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # Now we train the model
+ for epoch in range(starting_epoch, num_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We need to skip steps until we reach the resumed step
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ overall_step += resume_step
+ else:
+ # After the first iteration though, we need to go back to the original dataloader
+ active_dataloader = train_dataloader
+ for batch in active_dataloader:
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch = {k: v.to(accelerator.device) for k, v in batch.items()}
+ inputs = (batch["image"] - mean) / std
+ outputs = model(inputs)
+ loss = torch.nn.functional.cross_entropy(outputs, batch["label"])
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ overall_step += 1
+ if isinstance(checkpointing_steps, int):
+ output_dir = f"step_{overall_step}"
+ if overall_step % checkpointing_steps == 0:
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+ model.eval()
+ accurate = 0
+ num_elems = 0
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch = {k: v.to(accelerator.device) for k, v in batch.items()}
+ inputs = (batch["image"] - mean) / std
+ with torch.no_grad():
+ outputs = model(inputs)
+ predictions = outputs.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["label"]))
+ accurate_preds = predictions == references
+ num_elems += accurate_preds.shape[0]
+ accurate += accurate_preds.long().sum()
+
+ eval_metric = accurate.item() / num_elems
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}: {100 * eval_metric:.2f}")
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "accuracy": 100 * eval_metric,
+ "train_loss": total_loss.item() / len(train_dataloader),
+ "epoch": epoch,
+ },
+ step=overall_step,
+ )
+ if checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument("--data_dir", required=True, help="The data folder on disk.")
+ parser.add_argument("--fp16", action="store_true", help="If passed, will use FP16 training.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--output_dir",
+ type=str,
+ default=".",
+ help="Optional save directory where all checkpoint folders will be stored. Default is the current working directory.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--use_stateful_dataloader",
+ action="store_true",
+ help="If the dataloader should be a resumable stateful dataloader.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to load in all available experiment trackers from the environment and use them for logging.",
+ )
+ parser.add_argument(
+ "--project_dir",
+ type=str,
+ default="logs",
+ help="Location on where to store experiment tracking logs` and relevent project information",
+ )
+ args = parser.parse_args()
+ config = {"lr": 3e-2, "num_epochs": 3, "seed": 42, "batch_size": 64, "image_size": 224}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/complete_nlp_example.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/complete_nlp_example.py
new file mode 100644
index 0000000000000000000000000000000000000000..a692cb7b773bcedb06d1e70707a55898ffb43c03
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/complete_nlp_example.py
@@ -0,0 +1,324 @@
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import os
+
+import evaluate
+import torch
+from datasets import load_dataset
+from torch.optim import AdamW
+from torch.utils.data import DataLoader
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, get_linear_schedule_with_warmup, set_seed
+
+from accelerate import Accelerator, DataLoaderConfiguration, DistributedType
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate
+#
+# This example trains a Bert base model on GLUE MRPC
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# This example also demonstrates the checkpointing and sharding capabilities
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+
+MAX_GPU_BATCH_SIZE = 16
+EVAL_BATCH_SIZE = 32
+
+
+def training_function(config, args):
+ # Initialize accelerator
+ dataloader_config = DataLoaderConfiguration(use_stateful_dataloader=args.use_stateful_dataloader)
+ if args.with_tracking:
+ accelerator = Accelerator(
+ cpu=args.cpu,
+ mixed_precision=args.mixed_precision,
+ dataloader_config=dataloader_config,
+ log_with="all",
+ project_dir=args.project_dir,
+ )
+ else:
+ accelerator = Accelerator(
+ cpu=args.cpu, mixed_precision=args.mixed_precision, dataloader_config=dataloader_config
+ )
+
+ if hasattr(args.checkpointing_steps, "isdigit"):
+ if args.checkpointing_steps == "epoch":
+ checkpointing_steps = args.checkpointing_steps
+ elif args.checkpointing_steps.isdigit():
+ checkpointing_steps = int(args.checkpointing_steps)
+ else:
+ raise ValueError(
+ f"Argument `checkpointing_steps` must be either a number or `epoch`. `{args.checkpointing_steps}` passed."
+ )
+ else:
+ checkpointing_steps = None
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+
+ # We need to initialize the trackers we use, and also store our configuration
+ if args.with_tracking:
+ run = os.path.split(__file__)[-1].split(".")[0]
+ accelerator.init_trackers(run, config)
+
+ tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
+ datasets = load_dataset("glue", "mrpc")
+ metric = evaluate.load("glue", "mrpc")
+
+ def tokenize_function(examples):
+ # max_length=None => use the model max length (it's actually the default)
+ outputs = tokenizer(examples["sentence1"], examples["sentence2"], truncation=True, max_length=None)
+ return outputs
+
+ # Apply the method we just defined to all the examples in all the splits of the dataset
+ # starting with the main process first:
+ with accelerator.main_process_first():
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=["idx", "sentence1", "sentence2"],
+ )
+
+ # We also rename the 'label' column to 'labels' which is the expected name for labels by the models of the
+ # transformers library
+ tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+
+ # If the batch size is too big we use gradient accumulation
+ gradient_accumulation_steps = 1
+ if batch_size > MAX_GPU_BATCH_SIZE and accelerator.distributed_type != DistributedType.XLA:
+ gradient_accumulation_steps = batch_size // MAX_GPU_BATCH_SIZE
+ batch_size = MAX_GPU_BATCH_SIZE
+
+ def collate_fn(examples):
+ # On TPU it's best to pad everything to the same length or training will be very slow.
+ max_length = 128 if accelerator.distributed_type == DistributedType.XLA else None
+ # When using mixed precision we want round multiples of 8/16
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+
+ return tokenizer.pad(
+ examples,
+ padding="longest",
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(
+ tokenized_datasets["train"], shuffle=True, collate_fn=collate_fn, batch_size=batch_size
+ )
+ eval_dataloader = DataLoader(
+ tokenized_datasets["validation"], shuffle=False, collate_fn=collate_fn, batch_size=EVAL_BATCH_SIZE
+ )
+
+ set_seed(seed)
+
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased", return_dict=True)
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+
+ # Instantiate optimizer
+ optimizer = AdamW(params=model.parameters(), lr=lr)
+
+ # Instantiate scheduler
+ lr_scheduler = get_linear_schedule_with_warmup(
+ optimizer=optimizer,
+ num_warmup_steps=100,
+ num_training_steps=(len(train_dataloader) * num_epochs) // gradient_accumulation_steps,
+ )
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # We need to keep track of how many total steps we have iterated over
+ overall_step = 0
+ # We also need to keep track of the stating epoch so files are named properly
+ starting_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ accelerator.print(f"Resumed from checkpoint: {args.resume_from_checkpoint}")
+ accelerator.load_state(args.resume_from_checkpoint)
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ else:
+ resume_step = int(training_difference.replace("step_", ""))
+ starting_epoch = resume_step // len(train_dataloader)
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # Now we train the model
+ for epoch in range(starting_epoch, num_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We need to skip steps until we reach the resumed step
+ if not args.use_stateful_dataloader:
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+ overall_step += resume_step
+ else:
+ # After the first iteration though, we need to go back to the original dataloader
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ outputs = model(**batch)
+ loss = outputs.loss
+ loss = loss / gradient_accumulation_steps
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ accelerator.backward(loss)
+ if step % gradient_accumulation_steps == 0:
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ overall_step += 1
+
+ if isinstance(checkpointing_steps, int):
+ output_dir = f"step_{overall_step}"
+ if overall_step % checkpointing_steps == 0:
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch.to(accelerator.device)
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "accuracy": eval_metric["accuracy"],
+ "f1": eval_metric["f1"],
+ "train_loss": total_loss.item() / len(train_dataloader),
+ "epoch": epoch,
+ },
+ step=epoch,
+ )
+
+ if checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--use_stateful_dataloader",
+ action="store_true",
+ help="If the dataloader should be a resumable stateful dataloader.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to load in all available experiment trackers from the environment and use them for logging.",
+ )
+ parser.add_argument(
+ "--output_dir",
+ type=str,
+ default=".",
+ help="Optional save directory where all checkpoint folders will be stored. Default is the current working directory.",
+ )
+ parser.add_argument(
+ "--project_dir",
+ type=str,
+ default="logs",
+ help="Location on where to store experiment tracking logs` and relevent project information",
+ )
+ args = parser.parse_args()
+ config = {"lr": 2e-5, "num_epochs": 3, "seed": 42, "batch_size": 16}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/README.md b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..4cfd56f2ac5e2b6bc3579acfe29ef332d3d59e7e
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/README.md
@@ -0,0 +1,10 @@
+# Config Zoo
+
+This folder contains a variety of minimal configurations for `Accelerate` achieving certain goals. You can use these
+direct config YAML's, or build off of them for your own YAML's.
+
+These are highly annoted versions, aiming to teach you what each section does.
+
+Each config can be run via `accelerate launch --config_file {file} run_me.py`
+
+`run_me.py` will then print out how the current environment is setup (the contents of the `AcceleratorState`)
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/deepspeed.yaml b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/deepspeed.yaml
new file mode 100644
index 0000000000000000000000000000000000000000..eb24849b0f176bf72a796d7795f17a870247a23a
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/deepspeed.yaml
@@ -0,0 +1,15 @@
+# Similar to FSDP, we set the distributed type as DEEPSPEED
+distributed_type: DEEPSPEED
+# With DeepSpeed, we utilize a deepspeed config file for the entire configuration
+deepspeed_config:
+ # Can also be any of the config json's in accelerate/examples/deepspeed_config_templates
+ deepspeed_config_file: ../deepspeed_config_templates/zero_stage1_config.json
+ # If using ZeRO-3 and wanting to load big models in, this should be set to `true` so
+ # `transformers` uses the right `init` function
+ zero3_init_flag: false # true
+
+# Finally we need to specify the number of accelerators to use
+num_processes: 2
+# Optionally we can set the mixed precision now instead of in the deepspeed config file,
+# however this requires the `fp16` and `bf16` options to be set to `auto` in the deepspeed config file
+# mixed_precision: "bf16"
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/fp8.yaml b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/fp8.yaml
new file mode 100644
index 0000000000000000000000000000000000000000..c762a003d593abac7d4e8c60a15564950e31cd60
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/fp8.yaml
@@ -0,0 +1,18 @@
+# This config template simply setups up the TransformersEngine config (and a config for a single GPU),
+# this can interop with the other configs in this folder
+distributed_type: "NO"
+mixed_precision: "fp8"
+# Then we specify the fp8 configuration:
+fp8_config:
+ backend: TE # Can be TE | MS-AMP
+ # The following are TE specific arguments.
+ # See https://docs.nvidia.com/deeplearning/transformer-engine/user-guide/api/common.html#common-api for more details
+ amax_history_len: 1024
+ fp8_format: E4M3
+ interval: 1
+ margin: 0
+ override_linear_precision: [false, false, false]
+ # Generally this should always be set to `false` to have the most realistic fp8 eval performance
+ use_autocast_during_eval: false
+ # If using MS-AMP, we ignore all of the prior and set a opt_level
+ #opt_level: O1
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/fsdp.yaml b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/fsdp.yaml
new file mode 100644
index 0000000000000000000000000000000000000000..f5655a8775a35f586261d66ef3b086b61bbebd64
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/fsdp.yaml
@@ -0,0 +1,18 @@
+# Since we are doing FSDP (even though it's multi-accelerator), we need to specify the distributed type as FSDP
+distributed_type: FSDP
+# Can be one of "no", "fp16", or "bf16" (see `transformer_engine.yaml` for `fp8`, but it works for FSDP as well)
+mixed_precision: 'bf16'
+# Specify the number of accelerators to use
+num_processes: 2
+# Then we can specify the FSDP config
+fsdp_config:
+ fsdp_activation_checkpointing: false
+ fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
+ fsdp_backward_prefetch: BACKWARD_PRE
+ fsdp_cpu_ram_efficient_loading: true
+ fsdp_forward_prefetch: false
+ fsdp_offload_params: false
+ fsdp_sharding_strategy: FULL_SHARD
+ fsdp_state_dict_type: SHARDED_STATE_DICT
+ fsdp_sync_module_states: true
+ fsdp_use_orig_params: true
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/multi_gpu.yaml b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/multi_gpu.yaml
new file mode 100644
index 0000000000000000000000000000000000000000..9d6c12bf667960e3849231b26ebcf1ae9e5432f5
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/multi_gpu.yaml
@@ -0,0 +1,6 @@
+# Specify distributed_type as `MULTI_GPU` for DDP
+distributed_type: "MULTI_GPU"
+# Can be one of "no", "fp16", or "bf16" (see `transformer_engine.yaml` for `fp8`)
+mixed_precision: "bf16"
+# Specify the number of GPUs to use
+num_processes: 2
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/multi_node.yaml b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/multi_node.yaml
new file mode 100644
index 0000000000000000000000000000000000000000..b76699f849c815b6956eb5643ae0ea865f44ecf2
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/multi_node.yaml
@@ -0,0 +1,16 @@
+# This config template is for a multi-node setup. This assumes DDP, but can be interop'd with the other configs in this folder
+# Generally it's recommended to look at the SLURM config template for a more robust multi-node setup
+distributed_type: MULTI_GPU
+# We need to specify the current machine's rank
+machine_rank: 0
+# We then need to specify the IP address and port of the main process
+main_process_ip: '1234'
+main_process_port: 9999
+# We need to specify the number of machines
+num_machines: 2
+# We need to specify the *total* number of processes
+num_processes: 8
+# And then we need to specify how rdvz comms will be handled
+rdzv_backend: static # or c10d
+# If the compute nodes are on the same network (cloud will more than likely be false)
+same_network: false
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/multi_xpu.yaml b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/multi_xpu.yaml
new file mode 100644
index 0000000000000000000000000000000000000000..8db6802b065f06b188bc441accb40de997743b7f
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/multi_xpu.yaml
@@ -0,0 +1,6 @@
+# Specify distributed_type as `MULTI_XPU` for DDP
+distributed_type: "MULTI_XPU"
+# Can be one of "no", "fp16", or "bf16" (see `transformer_engine.yaml` for `fp8`)
+mixed_precision: "bf16"
+# Specify the number of XPUs to use
+num_processes: 2
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/run_me.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/run_me.py
new file mode 100644
index 0000000000000000000000000000000000000000..f016bc2bf5da86f6f4b628efcdfdcbf3c4ed6143
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/run_me.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+A base script which outputs the accelerate config for the given environment
+"""
+
+from accelerate import Accelerator
+
+
+accelerator = Accelerator()
+
+accelerator.print(f"Accelerator state from the current environment:\n{accelerator.state}")
+if accelerator.fp8_recipe_handler is not None:
+ accelerator.print(f"FP8 config:\n{accelerator.fp8_recipe_handler}")
+accelerator.end_training()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/single_accelerator.yaml b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/single_accelerator.yaml
new file mode 100644
index 0000000000000000000000000000000000000000..dbe4acadb6459ebe11500171b97e7f062205578a
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/config_yaml_templates/single_accelerator.yaml
@@ -0,0 +1,4 @@
+# Since this is single GPU/XPU, we don't need distributed training
+distributed_type: "NO"
+# Can be one of "no", "fp16", or "bf16" (see `transformer_engine.yaml` for `fp8`)
+mixed_precision: "bf16"
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/cv_example.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/cv_example.py
new file mode 100644
index 0000000000000000000000000000000000000000..f7e268ee661ccb5b89aa31f60e3b593d18b6294d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/cv_example.py
@@ -0,0 +1,209 @@
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import argparse
+import os
+import re
+
+import numpy as np
+import PIL
+import torch
+from timm import create_model
+from torch.optim.lr_scheduler import OneCycleLR
+from torch.utils.data import DataLoader, Dataset
+from torchvision.transforms import Compose, RandomResizedCrop, Resize, ToTensor
+
+from accelerate import Accelerator
+from accelerate.utils import set_seed
+
+
+########################################################################
+# This is a fully working simple example to use Accelerate
+#
+# This example trains a ResNet50 on the Oxford-IIT Pet Dataset
+# in any of the following settings (with the same script):
+# - single CPU or single GPU
+# - multi GPUS (using PyTorch distributed mode)
+# - (multi) TPUs
+# - fp16 (mixed-precision) or fp32 (normal precision)
+#
+# To run it in each of these various modes, follow the instructions
+# in the readme for examples:
+# https://github.com/huggingface/accelerate/tree/main/examples
+#
+########################################################################
+
+
+# Function to get the label from the filename
+def extract_label(fname):
+ stem = fname.split(os.path.sep)[-1]
+ return re.search(r"^(.*)_\d+\.jpg$", stem).groups()[0]
+
+
+class PetsDataset(Dataset):
+ def __init__(self, file_names, image_transform=None, label_to_id=None):
+ self.file_names = file_names
+ self.image_transform = image_transform
+ self.label_to_id = label_to_id
+
+ def __len__(self):
+ return len(self.file_names)
+
+ def __getitem__(self, idx):
+ fname = self.file_names[idx]
+ raw_image = PIL.Image.open(fname)
+ image = raw_image.convert("RGB")
+ if self.image_transform is not None:
+ image = self.image_transform(image)
+ label = extract_label(fname)
+ if self.label_to_id is not None:
+ label = self.label_to_id[label]
+ return {"image": image, "label": label}
+
+
+def training_function(config, args):
+ # Initialize accelerator
+ accelerator = Accelerator(cpu=args.cpu, mixed_precision=args.mixed_precision)
+
+ # Sample hyper-parameters for learning rate, batch size, seed and a few other HPs
+ lr = config["lr"]
+ num_epochs = int(config["num_epochs"])
+ seed = int(config["seed"])
+ batch_size = int(config["batch_size"])
+ image_size = config["image_size"]
+ if not isinstance(image_size, (list, tuple)):
+ image_size = (image_size, image_size)
+
+ # Grab all the image filenames
+ file_names = [os.path.join(args.data_dir, fname) for fname in os.listdir(args.data_dir) if fname.endswith(".jpg")]
+
+ # Build the label correspondences
+ all_labels = [extract_label(fname) for fname in file_names]
+ id_to_label = list(set(all_labels))
+ id_to_label.sort()
+ label_to_id = {lbl: i for i, lbl in enumerate(id_to_label)}
+
+ # Set the seed before splitting the data.
+ set_seed(seed)
+ # Split our filenames between train and validation
+ random_perm = np.random.permutation(len(file_names))
+ cut = int(0.8 * len(file_names))
+ train_split = random_perm[:cut]
+ eval_split = random_perm[cut:]
+
+ # For training we use a simple RandomResizedCrop
+ train_tfm = Compose([RandomResizedCrop(image_size, scale=(0.5, 1.0)), ToTensor()])
+ train_dataset = PetsDataset(
+ [file_names[i] for i in train_split], image_transform=train_tfm, label_to_id=label_to_id
+ )
+
+ # For evaluation, we use a deterministic Resize
+ eval_tfm = Compose([Resize(image_size), ToTensor()])
+ eval_dataset = PetsDataset([file_names[i] for i in eval_split], image_transform=eval_tfm, label_to_id=label_to_id)
+
+ # Instantiate dataloaders.
+ train_dataloader = DataLoader(train_dataset, shuffle=True, batch_size=batch_size, num_workers=4)
+ eval_dataloader = DataLoader(eval_dataset, shuffle=False, batch_size=batch_size, num_workers=4)
+
+ # Instantiate the model (we build the model here so that the seed also control new weights initialization)
+ model = create_model("resnet50d", pretrained=True, num_classes=len(label_to_id))
+
+ # We could avoid this line since the accelerator is set with `device_placement=True` (default value).
+ # Note that if you are placing tensors on devices manually, this line absolutely needs to be before the optimizer
+ # creation otherwise training will not work on TPU (`accelerate` will kindly throw an error to make us aware of that).
+ model = model.to(accelerator.device)
+
+ # Freezing the base model
+ for param in model.parameters():
+ param.requires_grad = False
+ for param in model.get_classifier().parameters():
+ param.requires_grad = True
+
+ # We normalize the batches of images to be a bit faster.
+ mean = torch.tensor(model.default_cfg["mean"])[None, :, None, None].to(accelerator.device)
+ std = torch.tensor(model.default_cfg["std"])[None, :, None, None].to(accelerator.device)
+
+ # Instantiate optimizer
+ optimizer = torch.optim.Adam(params=model.parameters(), lr=lr / 25)
+
+ # Instantiate learning rate scheduler
+ lr_scheduler = OneCycleLR(optimizer=optimizer, max_lr=lr, epochs=num_epochs, steps_per_epoch=len(train_dataloader))
+
+ # Prepare everything
+ # There is no specific order to remember, we just need to unpack the objects in the same order we gave them to the
+ # prepare method.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # Now we train the model
+ for epoch in range(num_epochs):
+ model.train()
+ for step, batch in enumerate(train_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch = {k: v.to(accelerator.device) for k, v in batch.items()}
+ inputs = (batch["image"] - mean) / std
+ outputs = model(inputs)
+ loss = torch.nn.functional.cross_entropy(outputs, batch["label"])
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ model.eval()
+ accurate = 0
+ num_elems = 0
+ for _, batch in enumerate(eval_dataloader):
+ # We could avoid this line since we set the accelerator with `device_placement=True`.
+ batch = {k: v.to(accelerator.device) for k, v in batch.items()}
+ inputs = (batch["image"] - mean) / std
+ with torch.no_grad():
+ outputs = model(inputs)
+ predictions = outputs.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["label"]))
+ accurate_preds = predictions == references
+ num_elems += accurate_preds.shape[0]
+ accurate += accurate_preds.long().sum()
+
+ eval_metric = accurate.item() / num_elems
+ # Use accelerator.print to print only on the main process.
+ accelerator.print(f"epoch {epoch}: {100 * eval_metric:.2f}")
+ accelerator.end_training()
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+ parser.add_argument("--data_dir", required=True, help="The data folder on disk.")
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16", "fp8"],
+ help="Whether to use mixed precision. Choose"
+ "between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >= 1.10."
+ "and an Nvidia Ampere GPU.",
+ )
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument("--cpu", action="store_true", help="If passed, will train on the CPU.")
+ args = parser.parse_args()
+ config = {"lr": 3e-2, "num_epochs": 3, "seed": 42, "batch_size": 64, "image_size": 224}
+ training_function(config, args)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/deepspeed_config_templates/zero_stage1_config.json b/tasks/tasksmith-3d762a2acfee/tests/source/examples/deepspeed_config_templates/zero_stage1_config.json
new file mode 100644
index 0000000000000000000000000000000000000000..674420e57fc21329cd466dc2a2e68f981c621bce
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/deepspeed_config_templates/zero_stage1_config.json
@@ -0,0 +1,43 @@
+{
+ "fp16": {
+ "enabled": true,
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ },
+ "optimizer": {
+ "type": "AdamW",
+ "params": {
+ "lr": "auto",
+ "weight_decay": "auto",
+ "torch_adam": true,
+ "adam_w_mode": true
+ }
+ },
+ "scheduler": {
+ "type": "WarmupDecayLR",
+ "params": {
+ "warmup_min_lr": "auto",
+ "warmup_max_lr": "auto",
+ "warmup_num_steps": "auto",
+ "total_num_steps": "auto"
+ }
+ },
+ "zero_optimization": {
+ "stage": 1,
+ "allgather_partitions": true,
+ "allgather_bucket_size": 2e8,
+ "overlap_comm": true,
+ "reduce_scatter": true,
+ "reduce_bucket_size": "auto",
+ "contiguous_gradients": true
+ },
+ "gradient_accumulation_steps": 1,
+ "gradient_clipping": "auto",
+ "steps_per_print": 2000,
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ "wall_clock_breakdown": false
+}
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/deepspeed_config_templates/zero_stage2_config.json b/tasks/tasksmith-3d762a2acfee/tests/source/examples/deepspeed_config_templates/zero_stage2_config.json
new file mode 100644
index 0000000000000000000000000000000000000000..9597f8485c1a96424ff91f88ab9d934c4ac07bb9
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/deepspeed_config_templates/zero_stage2_config.json
@@ -0,0 +1,43 @@
+{
+ "fp16": {
+ "enabled": true,
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ },
+ "optimizer": {
+ "type": "AdamW",
+ "params": {
+ "lr": "auto",
+ "weight_decay": "auto",
+ "torch_adam": true,
+ "adam_w_mode": true
+ }
+ },
+ "scheduler": {
+ "type": "WarmupDecayLR",
+ "params": {
+ "warmup_min_lr": "auto",
+ "warmup_max_lr": "auto",
+ "warmup_num_steps": "auto",
+ "total_num_steps": "auto"
+ }
+ },
+ "zero_optimization": {
+ "stage": 2,
+ "allgather_partitions": true,
+ "allgather_bucket_size": 2e8,
+ "overlap_comm": true,
+ "reduce_scatter": true,
+ "reduce_bucket_size": "auto",
+ "contiguous_gradients": true
+ },
+ "gradient_accumulation_steps": 1,
+ "gradient_clipping": "auto",
+ "steps_per_print": 2000,
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ "wall_clock_breakdown": false
+}
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/deepspeed_config_templates/zero_stage2_offload_config.json b/tasks/tasksmith-3d762a2acfee/tests/source/examples/deepspeed_config_templates/zero_stage2_offload_config.json
new file mode 100644
index 0000000000000000000000000000000000000000..98baedef38a86fe1cef3d5e1a8659b6b08eb275b
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/deepspeed_config_templates/zero_stage2_offload_config.json
@@ -0,0 +1,47 @@
+{
+ "fp16": {
+ "enabled": true,
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ },
+ "optimizer": {
+ "type": "AdamW",
+ "params": {
+ "lr": "auto",
+ "weight_decay": "auto",
+ "torch_adam": true,
+ "adam_w_mode": true
+ }
+ },
+ "scheduler": {
+ "type": "WarmupDecayLR",
+ "params": {
+ "warmup_min_lr": "auto",
+ "warmup_max_lr": "auto",
+ "warmup_num_steps": "auto",
+ "total_num_steps": "auto"
+ }
+ },
+ "zero_optimization": {
+ "stage": 2,
+ "offload_optimizer": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ "allgather_partitions": true,
+ "allgather_bucket_size": 2e8,
+ "overlap_comm": true,
+ "reduce_scatter": true,
+ "reduce_bucket_size": "auto",
+ "contiguous_gradients": true
+ },
+ "gradient_accumulation_steps": 1,
+ "gradient_clipping": "auto",
+ "steps_per_print": 2000,
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ "wall_clock_breakdown": false
+}
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/deepspeed_config_templates/zero_stage3_config.json b/tasks/tasksmith-3d762a2acfee/tests/source/examples/deepspeed_config_templates/zero_stage3_config.json
new file mode 100644
index 0000000000000000000000000000000000000000..2ec6fff41a79b4f1ad0d1849cbba640de67b113d
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/deepspeed_config_templates/zero_stage3_config.json
@@ -0,0 +1,44 @@
+{
+ "fp16": {
+ "enabled": true,
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ },
+ "optimizer": {
+ "type": "AdamW",
+ "params": {
+ "lr": "auto",
+ "weight_decay": "auto"
+ }
+ },
+ "scheduler": {
+ "type": "WarmupDecayLR",
+ "params": {
+ "warmup_min_lr": "auto",
+ "warmup_max_lr": "auto",
+ "warmup_num_steps": "auto",
+ "total_num_steps": "auto"
+ }
+ },
+ "zero_optimization": {
+ "stage": 3,
+ "overlap_comm": true,
+ "contiguous_gradients": true,
+ "reduce_bucket_size": "auto",
+ "stage3_prefetch_bucket_size": "auto",
+ "stage3_param_persistence_threshold": "auto",
+ "sub_group_size": 1e9,
+ "stage3_max_live_parameters": 1e9,
+ "stage3_max_reuse_distance": 1e9,
+ "stage3_gather_16bit_weights_on_model_save": "auto"
+ },
+ "gradient_accumulation_steps": 1,
+ "gradient_clipping": "auto",
+ "steps_per_print": 2000,
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ "wall_clock_breakdown": false
+}
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/deepspeed_config_templates/zero_stage3_offload_config.json b/tasks/tasksmith-3d762a2acfee/tests/source/examples/deepspeed_config_templates/zero_stage3_offload_config.json
new file mode 100644
index 0000000000000000000000000000000000000000..edae8e6286e632d40fffd990b39bbde5d7409c03
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/deepspeed_config_templates/zero_stage3_offload_config.json
@@ -0,0 +1,52 @@
+{
+ "fp16": {
+ "enabled": true,
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ },
+ "optimizer": {
+ "type": "AdamW",
+ "params": {
+ "lr": "auto",
+ "weight_decay": "auto"
+ }
+ },
+ "scheduler": {
+ "type": "WarmupDecayLR",
+ "params": {
+ "warmup_min_lr": "auto",
+ "warmup_max_lr": "auto",
+ "warmup_num_steps": "auto",
+ "total_num_steps": "auto"
+ }
+ },
+ "zero_optimization": {
+ "stage": 3,
+ "offload_optimizer": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ "offload_param": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ "overlap_comm": true,
+ "contiguous_gradients": true,
+ "reduce_bucket_size": "auto",
+ "stage3_prefetch_bucket_size": "auto",
+ "stage3_param_persistence_threshold": "auto",
+ "sub_group_size": 1e9,
+ "stage3_max_live_parameters": 1e9,
+ "stage3_max_reuse_distance": 1e9,
+ "stage3_gather_16bit_weights_on_model_save": "auto"
+ },
+ "gradient_accumulation_steps": 1,
+ "gradient_clipping": "auto",
+ "steps_per_print": 2000,
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ "wall_clock_breakdown": false
+}
\ No newline at end of file
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/finetune_lm_tpu.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/finetune_lm_tpu.py
new file mode 100644
index 0000000000000000000000000000000000000000..ed8180d5092b7cc6531000fc2d264f0dfa207524
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/finetune_lm_tpu.py
@@ -0,0 +1,170 @@
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+# Example of fine-tuning a model on a TPU using FSDPv2, TRL and PEFT.
+#
+# Run the script with:
+# python finetune_lm_tpu.py [--model_id MODEL_ID] [--dataset_id DATASET_ID]
+#
+# This script has been tested on a TPU v5 litepod-8.
+
+import argparse
+
+import torch
+import torch_xla.runtime as xr
+from datasets import load_dataset
+from peft import LoraConfig
+from transformers import AutoModelForCausalLM, AutoTokenizer
+from trl import SFTConfig, SFTTrainer
+
+
+# FSDPv2 requires SPMD to be enabled.
+xr.use_spmd()
+
+
+def format_dolly(example, tokenizer):
+ """Format Dolly dataset examples using the tokenizer's chat template."""
+ user_content = example["instruction"]
+ if len(example["context"]) > 0:
+ user_content += f"\n\nContext: {example['context']}"
+
+ messages = [
+ {
+ "role": "system",
+ "content": "You are a helpful assistant",
+ },
+ {"role": "user", "content": user_content},
+ {"role": "assistant", "content": example["response"]},
+ ]
+
+ return tokenizer.apply_chat_template(messages, tokenize=False)
+
+
+def train(model_id, dataset):
+ # Load model with low_cpu_mem_usage to avoid loading full model into CPU memory
+ # FSDPv2 will handle sharding across TPUs
+ model = AutoModelForCausalLM.from_pretrained(
+ model_id,
+ use_cache=False,
+ torch_dtype=torch.bfloat16,
+ low_cpu_mem_usage=True,
+ device_map=None, # Let FSDP handle device placement
+ )
+
+ tokenizer = AutoTokenizer.from_pretrained(model_id)
+
+ if tokenizer.pad_token is None:
+ if model.config.model_type == "llama":
+ # Vanilla Llama models have a finetune gith pad id token
+ tokenizer.pad_token = "<|finetune_right_pad_id|>"
+ elif tokenizer.eos_token is not None:
+ tokenizer.pad_token = tokenizer.eos_token
+ else:
+ raise ValueError(f"Cannot get or guess pad token for model {model_id}.")
+
+ if tokenizer.chat_template is None:
+ # Set chat template for Llama 3.1 format
+ tokenizer.chat_template = (
+ "{% for message in messages %}"
+ "{% if message['role'] == 'system' %}"
+ "<|begin_of_text|><|start_header_id|>system<|end_header_id|>\n\n{{ message['content'] }}<|eot_id|>"
+ "{% elif message['role'] == 'user' %}"
+ "<|start_header_id|>user<|end_header_id|>\n\n{{ message['content'] }}<|eot_id|>"
+ "{% elif message['role'] == 'assistant' %}"
+ "<|start_header_id|>assistant<|end_header_id|>\n\n{{ message['content'] }}<|eot_id|>"
+ "{% endif %}"
+ "{% endfor %}"
+ "{% if add_generation_prompt %}"
+ "<|start_header_id|>assistant<|end_header_id|>\n\n"
+ "{% endif %}"
+ )
+
+ # Try to guess the DecoderLayer class name, based on common model architectures
+ transformer_layer_cls_to_wrap = model.model.layers[0].__class__.__name__
+
+ # Get FSDP training arguments
+ fsdp_training_args = {
+ "fsdp": "full_shard",
+ "fsdp_config": {
+ "transformer_layer_cls_to_wrap": [transformer_layer_cls_to_wrap],
+ "xla": True,
+ "xla_fsdp_v2": True,
+ "xla_fsdp_grad_ckpt": True,
+ },
+ }
+
+ # Set up PEFT LoRA for fine-tuning.
+ lora_config = LoraConfig(
+ r=32,
+ lora_alpha=128,
+ lora_dropout=0.05,
+ target_modules=["q_proj", "k_proj"],
+ task_type="CAUSAL_LM",
+ )
+
+ sft_config = SFTConfig(
+ gradient_checkpointing=False, # Required on TPU, not supported
+ max_length=1024,
+ per_device_train_batch_size=4,
+ num_train_epochs=3,
+ max_steps=-1,
+ output_dir="./output",
+ optim="adafactor",
+ logging_steps=1,
+ dataloader_drop_last=True, # Required for FSDPv2.
+ dataset_text_field="text",
+ packing=True,
+ **fsdp_training_args,
+ )
+
+ # Set up the trainer
+ trainer = SFTTrainer(
+ model=model,
+ train_dataset=dataset,
+ args=sft_config,
+ peft_config=lora_config,
+ processing_class=tokenizer,
+ formatting_func=lambda example: format_dolly(example, tokenizer),
+ )
+
+ trainer.train()
+
+
+# =============================================================================
+# Main Function
+# =============================================================================
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser(description="Simple example of training script.")
+
+ parser.add_argument(
+ "--model_id", "-m", type=str, default="meta-llama/Llama-3.2-1B", help="Model id to use for training."
+ )
+ parser.add_argument(
+ "--dataset_id",
+ "-d",
+ type=str,
+ default="databricks/databricks-dolly-15k",
+ help="Dataset id to use for training.",
+ )
+
+ args = parser.parse_args()
+
+ # NOTE: this section can be adapted to load any dataset you want.
+ dataset_id = args.dataset_id
+ dolly_dataset = load_dataset(dataset_id, split="train")
+
+ train(
+ model_id=args.model_id,
+ dataset=dolly_dataset,
+ )
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/inference/distributed/README.md b/tasks/tasksmith-3d762a2acfee/tests/source/examples/inference/distributed/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..92828e7d94164360aeb5c58fb73de469ede2e75f
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/inference/distributed/README.md
@@ -0,0 +1,25 @@
+# Distributed inference examples
+
+This folder contains a variety of tutorials for running distributed inference with the following strategy:
+
+Load an entire model onto each GPU and sending chunks of a batch through each GPU’s model copy at a time
+
+## Installation
+
+```bash
+pip install accelerate torch
+```
+
+## Running code
+
+You can either use `torchrun` or the recommended way of `accelerate launch` (without needing to run `accelerate config`) on each script:
+
+```bash
+accelerate launch --num_processes {NUM_GPUS} phi2.py
+```
+
+Or:
+
+```bash
+torchrun --nproc-per-node {NUM_GPUS} phi2.py
+```
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/inference/distributed/distributed_image_generation.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/inference/distributed/distributed_image_generation.py
new file mode 100644
index 0000000000000000000000000000000000000000..68997e9e11ffa70ecd63379c19f622c2f4fc85a1
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/inference/distributed/distributed_image_generation.py
@@ -0,0 +1,117 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+Originally by jiwooya1000, put together together by sayakpaul.
+Documentation: https://huggingface.co/docs/diffusers/main/en/training/distributed_inference
+
+Run:
+
+accelerate launch distributed_image_generation.py --batch_size 8
+
+# Enable memory optimizations for large models like SD3
+accelerate launch distributed_image_generation.py --batch_size 8 --low_mem
+"""
+
+import os
+import time
+
+import fire
+import torch
+from datasets import load_dataset
+from diffusers import DiffusionPipeline
+from tqdm import tqdm
+
+from accelerate import PartialState
+from accelerate.utils import gather_object
+
+
+START_TIME = time.strftime("%Y%m%d_%H%M%S")
+DTYPE_MAP = {"fp32": torch.float32, "fp16": torch.float16, "bf16": torch.bfloat16}
+
+
+def get_batches(items, batch_size):
+ num_batches = (len(items) + batch_size - 1) // batch_size
+ batches = []
+
+ for i in range(num_batches):
+ start_index = i * batch_size
+ end_index = min((i + 1) * batch_size, len(items))
+ batch = items[start_index:end_index]
+ batches.append(batch)
+
+ return batches
+
+
+def main(
+ ckpt_id: str = "PixArt-alpha/PixArt-Sigma-XL-2-1024-MS",
+ save_dir: str = "./evaluation/examples",
+ seed: int = 1,
+ batch_size: int = 4,
+ num_inference_steps: int = 20,
+ guidance_scale: float = 4.5,
+ dtype: str = "fp16",
+ low_mem: bool = False,
+):
+ pipeline = DiffusionPipeline.from_pretrained(ckpt_id, torch_dtype=DTYPE_MAP[dtype])
+
+ save_dir = save_dir + f"_{START_TIME}"
+
+ parti_prompts = load_dataset("nateraw/parti-prompts", split="train")
+ data_loader = get_batches(items=parti_prompts["Prompt"], batch_size=batch_size)
+
+ distributed_state = PartialState()
+ if low_mem:
+ pipeline.enable_model_cpu_offload(gpu_id=distributed_state.device.index)
+ else:
+ pipeline = pipeline.to(distributed_state.device)
+
+ if distributed_state.is_main_process:
+ if not os.path.exists(save_dir):
+ os.makedirs(save_dir)
+ print(f"Directory '{save_dir}' created successfully.")
+ else:
+ print(f"Directory '{save_dir}' already exists.")
+
+ count = 0
+ for _, prompts_raw in tqdm(enumerate(data_loader), total=len(data_loader)):
+ input_prompts = []
+
+ with distributed_state.split_between_processes(prompts_raw) as prompts:
+ generator = torch.manual_seed(seed)
+ images = pipeline(
+ prompts, num_inference_steps=num_inference_steps, guidance_scale=guidance_scale, generator=generator
+ ).images
+ input_prompts.extend(prompts)
+
+ distributed_state.wait_for_everyone()
+
+ images = gather_object(images)
+ input_prompts = gather_object(input_prompts)
+
+ if distributed_state.is_main_process:
+ for image, prompt in zip(images, input_prompts):
+ count += 1
+ temp_dir = os.path.join(save_dir, f"example_{count}")
+
+ os.makedirs(temp_dir)
+ prompt = "_".join(prompt.split())
+ image.save(f"image_{prompt}.png")
+
+ if distributed_state.is_main_process:
+ print(f">>> Image Generation Finished. Saved in {save_dir}")
+
+
+if __name__ == "__main__":
+ fire.Fire(main)
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/inference/distributed/distributed_speech_generation.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/inference/distributed/distributed_speech_generation.py
new file mode 100644
index 0000000000000000000000000000000000000000..f44346c533fa0f5d9d9e6c7156b69996102f8f55
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/inference/distributed/distributed_speech_generation.py
@@ -0,0 +1,234 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+
+import json
+import os
+import pathlib
+import queue
+from concurrent.futures import ThreadPoolExecutor
+from typing import Union
+
+import fire
+import scipy.io.wavfile
+import torch
+from datasets import load_dataset
+from transformers import AutoTokenizer, VitsModel
+
+from accelerate import PartialState
+from accelerate.utils import tqdm
+
+
+"""
+Requirements: transformers accelerate fire scipy datasets
+pip install transformers accelerate fire scipy datasets
+Example usage:
+accelerate launch distributed_speech_generation.py --output_path outputs --batch_size 8 --num_workers 2 --dataset_split train
+"""
+
+"""
+To run the speech generation
+import scipy.io.wavfile
+import numpy as np
+from IPython.display import Audio
+sample_rate, audio_data = scipy.io.wavfile.read('path_to_you_wav_file.wav')
+audio_data = audio_data.astype(np.float32) / 32762.0
+Audio(audio_data, rate=sample_rate)
+"""
+
+
+def load_pokemon_data(split: str, max_text_length: int):
+ """Load Pokemon descriptions from the dataset"""
+ ds = load_dataset("svjack/pokemon-blip-captions-en-zh", split=split)
+
+ # Create dataset of dictionaries
+ dataset = []
+ for idx, text in enumerate(ds["en_text"]):
+ if len(text.strip()) > 0: # Skip empty descriptions
+ dataset.append(
+ {
+ "id": f"pokemon_{idx:06d}",
+ "text": text.strip()[:max_text_length], # Truncate long descriptions
+ "original_text": text.strip(), # Keep original for metadata
+ }
+ )
+ return dataset
+
+
+class ExistsFilter:
+ def __init__(self, output_dir: Union[pathlib.Path, str]):
+ current_files = [f.split(".wav")[0] for f in os.listdir(output_dir) if f.endswith(".wav")]
+ self.processed_files = set(current_files)
+ print(f"Existing audio files found: {len(self.processed_files)}.")
+
+ def __call__(self, x):
+ return x["id"] not in self.processed_files
+
+
+def preprocess_fn(sample, tokenizer, max_text_length: int):
+ inputs = tokenizer(sample["text"], padding=False, truncation=True, max_length=max_text_length, return_tensors="pt")
+
+ return {
+ "input_ids": inputs["input_ids"][0].tolist(),
+ "attention_mask": inputs["attention_mask"][0].tolist(),
+ "id": sample["id"],
+ "text": sample["text"],
+ "original_text": sample["original_text"],
+ }
+
+
+def collate_fn(examples, tokenizer):
+ """Collate batch of examples with proper padding"""
+ # Find max length in this batch
+ max_length = max(len(example["input_ids"]) for example in examples)
+
+ # Pad sequences to max_length
+ input_ids_list = []
+ attention_mask_list = []
+
+ for example in examples:
+ # Get current lengths
+ curr_len = len(example["input_ids"])
+ padding_length = max_length - curr_len
+
+ # Pad sequences
+ padded_input_ids = example["input_ids"] + [tokenizer.pad_token_id] * padding_length
+ padded_attention_mask = example["attention_mask"] + [0] * padding_length
+
+ input_ids_list.append(padded_input_ids)
+ attention_mask_list.append(padded_attention_mask)
+
+ # Convert to tensors
+ input_ids = torch.tensor(input_ids_list, dtype=torch.long)
+ attention_mask = torch.tensor(attention_mask_list, dtype=torch.long)
+
+ ids = [example["id"] for example in examples]
+ texts = [example["text"] for example in examples]
+ original_texts = [example["original_text"] for example in examples]
+
+ return {
+ "input_ids": input_ids,
+ "attention_mask": attention_mask,
+ "ids": ids,
+ "texts": texts,
+ "original_texts": original_texts,
+ }
+
+
+def create_dataloader(dataset, batch_size, distributed_state, tokenizer):
+ """Create dataloader with preprocessing"""
+ processed_dataset = [preprocess_fn(item, tokenizer, max_text_length=200) for item in dataset]
+
+ # Split dataset for distributed processing
+ if distributed_state.num_processes > 1:
+ chunk_size = len(processed_dataset) // distributed_state.num_processes
+ start_idx = distributed_state.process_index * chunk_size
+ end_idx = (
+ start_idx + chunk_size
+ if distributed_state.process_index < distributed_state.num_processes - 1
+ else len(processed_dataset)
+ )
+ processed_dataset = processed_dataset[start_idx:end_idx]
+
+ # Create batches
+ batches = []
+ for i in range(0, len(processed_dataset), batch_size):
+ batch = processed_dataset[i : i + batch_size]
+ batches.append(collate_fn(batch, tokenizer))
+ return batches
+
+
+def save_results(output_queue: queue.Queue, output_dir: pathlib.Path, sampling_rate: int):
+ while True:
+ try:
+ item = output_queue.get(timeout=5)
+ if item is None:
+ break
+ waveforms, ids, texts, original_texts = item
+
+ # Save each audio file and its metadata
+ for waveform, file_id, text, original_text in zip(waveforms, ids, texts, original_texts):
+ # Save audio
+ wav_path = output_dir / f"{file_id}.wav"
+ scipy.io.wavfile.write(wav_path, rate=sampling_rate, data=waveform.cpu().float().numpy())
+
+ # Save metadata with both truncated and original text
+ metadata = {
+ "text_used": text,
+ "original_text": original_text,
+ "model": "facebook/mms-tts-eng",
+ "sampling_rate": sampling_rate,
+ }
+ metadata_path = output_dir / f"{file_id}_metadata.json"
+ with metadata_path.open("w") as f:
+ json.dump(metadata, f, indent=4)
+
+ except queue.Empty:
+ continue
+
+
+def main(
+ output_path: str = "speech_data",
+ batch_size: int = 8,
+ num_workers: int = 2,
+ dataset_split: str = "train",
+ model_name: str = "facebook/mms-tts-eng",
+ max_text_length: int = 200,
+):
+ output_dir = pathlib.Path(output_path)
+ output_dir.mkdir(parents=True, exist_ok=True)
+ distributed_state = PartialState()
+
+ # Load model and tokenizer
+ model = VitsModel.from_pretrained(
+ model_name,
+ device_map=distributed_state.device,
+ torch_dtype=torch.float32,
+ )
+
+ tokenizer = AutoTokenizer.from_pretrained(model_name)
+
+ # Load and filter data
+ dataset = load_pokemon_data(dataset_split, max_text_length)
+ exist_filter = ExistsFilter(output_dir)
+ dataset = [item for item in dataset if exist_filter(item)]
+
+ distributed_state.print(f"Processing {len(dataset)} Pokemon descriptions")
+
+ # Create dataloader
+ batches = create_dataloader(dataset, batch_size, distributed_state, tokenizer)
+
+ # Setup output queue and save thread
+ output_queue = queue.Queue()
+ save_thread = ThreadPoolExecutor(max_workers=num_workers)
+ save_future = save_thread.submit(save_results, output_queue, output_dir, model.config.sampling_rate)
+
+ try:
+ for batch in tqdm(batches, desc="Generating Pokemon descriptions"):
+ with torch.no_grad():
+ outputs = model(
+ input_ids=batch["input_ids"].to(distributed_state.device, dtype=torch.long),
+ attention_mask=batch["attention_mask"].to(distributed_state.device, dtype=torch.long),
+ ).waveform
+
+ output_queue.put((outputs, batch["ids"], batch["texts"], batch["original_texts"]))
+ finally:
+ output_queue.put(None)
+ save_thread.shutdown(wait=True)
+
+ save_future.result()
+
+
+if __name__ == "__main__":
+ fire.Fire(main)
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/inference/distributed/florence2.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/inference/distributed/florence2.py
new file mode 100644
index 0000000000000000000000000000000000000000..3f17ce6bcc140f1accc2777f19d990b554eb5f26
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/inference/distributed/florence2.py
@@ -0,0 +1,202 @@
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import json
+import os
+import pathlib
+import queue
+from concurrent.futures import ThreadPoolExecutor
+from functools import partial
+from typing import Union
+
+import fire
+import torch
+import webdataset as wds
+from huggingface_hub.utils import insecure_hashlib
+from PIL import Image
+from tqdm import tqdm
+from transformers import AutoModelForCausalLM, AutoProcessor
+
+from accelerate import PartialState
+
+
+"""
+Additional requirements: flash_attn einops timm webdataset fire tqdm huggingface_hub
+pip install flash_attn einops timm webdataset fire tqdm huggingface_hub
+
+Example:
+
+accelerate launch --num_processes=2 florence2.py --data_path "https://huggingface.co/datasets/pixparse/cc3m-wds/resolve/main/cc3m-train-0000.tar" --output_path outputs --batch_size 12 --num_workers 1 --prompt "
"
+"""
+
+
+def main(
+ data_path: str,
+ output_path: str,
+ batch_size: int,
+ num_workers: int,
+ prompt: str = "",
+ model_name: str = "microsoft/Florence-2-large",
+ max_new_tokens: int = 1024,
+ num_beams: int = 3,
+):
+ output_dir = pathlib.Path(output_path)
+
+ distributed_state = PartialState()
+
+ if distributed_state.is_main_process:
+ output_dir.mkdir(exist_ok=True)
+
+ model = AutoModelForCausalLM.from_pretrained(
+ model_name,
+ device_map=distributed_state.device,
+ torch_dtype=torch.float16,
+ trust_remote_code=True,
+ )
+
+ processor = AutoProcessor.from_pretrained(model_name, trust_remote_code=True, clean_up_tokenization_spaces=True)
+
+ class ExistsFilter:
+ def __init__(self, output_dir: Union[pathlib.Path, str]):
+ current_training_img_hashes = [f.split(".jpg")[0] for f in os.listdir(output_dir) if f.endswith(".jpg")]
+ self.current_training_img_hashes = set(current_training_img_hashes)
+ if distributed_state.is_main_process:
+ print(f"Existing images found: {len(self.current_training_img_hashes)}.")
+
+ def __call__(self, x):
+ if len(self.current_training_img_hashes) > 0:
+ if x["img_hash"] in self.current_training_img_hashes:
+ return False
+ else:
+ return True
+ else:
+ return True
+
+ def preprocess_fn(sample, processor):
+ image: Image.Image = sample["jpg"].convert("RGB")
+ img_hash = insecure_hashlib.sha1(image.tobytes()).hexdigest()
+ inputs = processor(
+ text=prompt,
+ images=image,
+ return_tensors="pt",
+ )
+ return {
+ "input_ids": inputs["input_ids"],
+ "pixel_values": inputs["pixel_values"],
+ "image": image,
+ "img_hash": img_hash,
+ "original_caption": sample["txt"],
+ }
+
+ def collate_fn(examples):
+ input_ids = torch.cat([example["input_ids"] for example in examples])
+ pixel_values = torch.cat([example["pixel_values"] for example in examples])
+ images = [example["image"] for example in examples]
+ img_hashes = [example["img_hash"] for example in examples]
+ captions = [example["original_caption"] for example in examples]
+ return {
+ "input_ids": input_ids,
+ "pixel_values": pixel_values,
+ "images": images,
+ "img_hashes": img_hashes,
+ "original_captions": captions,
+ }
+
+ exist_filter = ExistsFilter(output_dir)
+ dataset = (
+ wds.WebDataset(
+ data_path,
+ handler=wds.warn_and_continue,
+ nodesplitter=None,
+ shardshuffle=False,
+ empty_check=False,
+ )
+ .decode("pil", handler=wds.warn_and_continue)
+ .map(partial(preprocess_fn, processor=processor), handler=wds.warn_and_continue)
+ )
+ if len(exist_filter.current_training_img_hashes) > 0:
+ dataset = dataset.select(exist_filter)
+ dataset = dataset.batched(
+ batch_size,
+ partial=False,
+ collation_fn=collate_fn,
+ )
+ dataloader = wds.WebLoader(
+ dataset,
+ batch_size=None,
+ num_workers=num_workers,
+ pin_memory=True,
+ persistent_workers=True,
+ )
+
+ def save_results(output_queue: queue.Queue, output_dir: pathlib.Path, processor):
+ while True:
+ try:
+ item = output_queue.get(timeout=5)
+ if item is None:
+ break
+ original_captions, predictions, images, img_hashes = item
+ predicted_captions = processor.batch_decode(
+ predictions,
+ skip_special_tokens=False,
+ )
+ for caption, pred_caption, image, img_hash in zip(
+ original_captions, predicted_captions, images, img_hashes
+ ):
+ processed_caption = processor.post_process_generation(
+ pred_caption, task=prompt, image_size=(image.width, image.height)
+ )[prompt]
+ img_path = output_dir.joinpath(f"{img_hash}.jpg")
+ image.save(img_path)
+
+ caption_dict = {"original": caption, "predicted": processed_caption}
+ with output_dir.joinpath(f"{img_hash}_caption.json").open("w") as f:
+ json.dump(caption_dict, f, indent=4)
+
+ except queue.Empty:
+ continue
+
+ output_queue = queue.Queue()
+ save_thread = ThreadPoolExecutor(max_workers=num_workers)
+ save_future = save_thread.submit(save_results, output_queue, output_dir, processor)
+
+ try:
+ for _, batch_raw in tqdm(
+ enumerate(dataloader),
+ disable=not distributed_state.is_main_process,
+ ):
+ with distributed_state.split_between_processes(batch_raw) as batch:
+ outputs = model.generate(
+ input_ids=batch["input_ids"].to(distributed_state.device),
+ pixel_values=batch["pixel_values"].to(distributed_state.device, model.dtype),
+ max_new_tokens=max_new_tokens,
+ num_beams=num_beams,
+ )
+ output_queue.put(
+ (
+ batch["original_captions"],
+ outputs,
+ batch["images"],
+ batch["img_hashes"],
+ )
+ )
+ finally:
+ output_queue.put(None)
+ save_thread.shutdown(wait=True)
+
+ save_future.result()
+
+
+if __name__ == "__main__":
+ fire.Fire(main)
diff --git a/tasks/tasksmith-3d762a2acfee/tests/source/examples/inference/distributed/llava_next_video.py b/tasks/tasksmith-3d762a2acfee/tests/source/examples/inference/distributed/llava_next_video.py
new file mode 100644
index 0000000000000000000000000000000000000000..10044293ee0801e8b5201eb6e86a8efbb3a3f77e
--- /dev/null
+++ b/tasks/tasksmith-3d762a2acfee/tests/source/examples/inference/distributed/llava_next_video.py
@@ -0,0 +1,192 @@
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import json
+import os
+import pathlib
+import queue
+import time
+from concurrent.futures import ThreadPoolExecutor
+
+import av
+import fire
+import numpy as np
+import torch
+from huggingface_hub import snapshot_download
+from tqdm import tqdm
+from transformers import LlavaNextVideoForConditionalGeneration, LlavaNextVideoProcessor
+
+from accelerate import PartialState
+
+
+START_TIME = time.strftime("%Y%m%d_%H%M%S")
+DTYPE_MAP = {"fp32": torch.float32, "fp16": torch.float16, "bf16": torch.bfloat16}
+
+
+"""
+Example:
+
+accelerate launch llava_next_video.py
+"""
+
+
+def save_results(output_queue: queue.Queue, output_dir: pathlib.Path):
+ count = 0
+ while True:
+ try:
+ item = output_queue.get(timeout=5)
+ if item is None:
+ break
+ prompt, video, generated_text = item
+ example_file = f"example_{count}"
+ temp_dir = os.path.join(output_dir, example_file)
+
+ metadata = {"prompt": prompt, "video": video, "generated_text": generated_text}
+ with open(temp_dir, "w") as f:
+ json.dump(metadata, f, indent=4)
+ count += 1
+
+ except queue.Empty:
+ continue
+
+
+def get_batches(processed_videos, batch_size):
+ num_batches = (len(processed_videos) + batch_size - 1) // batch_size
+ batches = []
+
+ for i in range(num_batches):
+ start_index = i * batch_size
+ end_index = min((i + 1) * batch_size, len(processed_videos))
+ batch = processed_videos[start_index:end_index]
+ batches.append(batch)
+
+ return batches
+
+
+def read_video_pyav(container, indices):
+ """
+ Decode the video with PyAV decoder.
+ Args:
+ container (`av.container.input.InputContainer`): PyAV container.
+ indices (`List[int]`): List of frame indices to decode.
+ Returns:
+ result (np.ndarray): np array of decoded frames of shape (num_frames, height, width, 3).
+ """
+ frames = []
+ container.seek(0)
+ start_index = indices[0]
+ end_index = indices[-1]
+ for i, frame in enumerate(container.decode(video=0)):
+ if i > end_index:
+ break
+ if i >= start_index and i in indices:
+ frames.append(frame)
+ return np.stack([x.to_ndarray(format="rgb24") for x in frames])
+
+
+def get_video_paths(video_dir):
+ """Get paths to all video files in the directory and its subdirectories."""
+ video_extensions = (".mp4", ".avi", ".mov", ".mkv") # Add more extensions if needed
+ video_paths = []
+
+ for root, _, files in os.walk(video_dir):
+ for file in files:
+ if file.lower().endswith(video_extensions):
+ video_paths.append(os.path.join(root, file))
+
+ return video_paths
+
+
+def process_videos(video_paths, processor, prompt, frames_per_video):
+ """Process a batch of videos and prepare them for the model."""
+ batch_inputs = []
+
+ for video_path in video_paths:
+ try:
+ with av.open(video_path) as container:
+ total_frames = container.streams.video[0].frames
+ indices = np.arange(0, total_frames, total_frames / frames_per_video).astype(int)
+ clip = read_video_pyav(container, indices)
+
+ processed = processor(text=prompt, videos=clip, return_tensors="pt")
+ batch_inputs.append(
+ {
+ "input_ids": processed["input_ids"],
+ "pixel_values_videos": processed["pixel_values_videos"],
+ "video": video_path,
+ }
+ )
+
+ except Exception as e:
+ print(f"Error processing video {video_path}: {str(e)}")
+ continue
+
+ return batch_inputs
+
+
+def main(
+ model_name: str = "llava-hf/LLaVA-NeXT-Video-7B-hf",
+ save_dir: str = "./evaluation/examples",
+ prompt: str = "USER:
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +