diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/swin.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/swin.md
new file mode 100644
index 0000000000000000000000000000000000000000..6919d7e9978e07af4938c633cedb22f80667d9a1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/swin.md
@@ -0,0 +1,95 @@
+
+
+# Swin Transformer [[swin-transformer]]
+
+## 개요 [[overview]]
+
+Swin Transformer는 Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo가 제안한 논문 [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030)에서 소개되었습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*이 논문은 Swin Transformer라는 새로운 비전 트랜스포머를 소개합니다. 이 모델은 컴퓨터 비전에서 범용 백본(backbone)으로 사용될 수 있습니다. 트랜스포머를 언어에서 비전으로 적용할 때의 어려움은 두 분야 간의 차이에서 비롯되는데, 예를 들어 시각적 객체의 크기가 크게 변동하며, 이미지의 픽셀 해상도가 텍스트의 단어에 비해 매우 높다는 점이 있습니다. 이러한 차이를 해결하기 위해, 우리는 'Shifted Windows'를 이용해 표현을 계산하는 계층적 트랜스포머를 제안합니다. Shifted Windows 방식은 겹치지 않는 로컬 윈도우에서 self-attention 계산을 제한하여 효율성을 높이는 동시에 윈도우 간 연결을 가능하게 합니다. 이 계층적 구조는 다양한 크기의 패턴을 모델링할 수 있는 유연성을 제공하며, 이미지 크기에 비례한 선형 계산 복잡성을 가지고 있습니다. Swin Transformer의 이러한 특징들은 이미지 분류(Imagenet-1K에서 87.3의 top-1 정확도) 및 객체 검출(COCO test-dev에서 58.7의 박스 AP, 51.1의 마스크 AP)과 같은 밀집 예측 작업, 의미적 분할(ADE20K val에서 53.5의 mIoU)과 같은 광범위한 비전 작업에 적합합니다. 이 모델은 COCO에서 이전 최고 성능을 박스 AP에서 +2.7, 마스크 AP에서 +2.6, ADE20K에서 mIoU에서 +3.2를 초과하는 성과를 보여주며, 트랜스포머 기반 모델이 비전 백본으로서의 잠재력을 입증했습니다. 계층적 설계와 Shifted Windows 방식은 순수 MLP 아키텍처에도 유리하게 작용합니다.*
+
+ Swin Transformer 아키텍처. 원본 논문 에서 발췌.
+
+이 모델은 [novice03](https://huggingface.co/novice03)이 기여하였습니다. Tensorflow 버전은 [amyeroberts](https://huggingface.co/amyeroberts)가 기여했습니다. 원본 코드는 [여기](https://github.com/microsoft/Swin-Transformer)에서 확인할 수 있습니다.
+
+## 사용 팁 [[usage-tips]]
+
+- Swin은 입력의 높이와 너비가 `32`로 나누어질 수 있으면 어떤 크기든 지원할 수 있도록 패딩을 추가합니다.
+- Swin은 *백본*으로 사용할 수 있습니다. `output_hidden_states = True`로 설정하면, `hidden_states`와 `reshaped_hidden_states`를 모두 출력합니다. `reshaped_hidden_states`는 `(batch, num_channels, height, width)` 형식을 가지며, 이는 `(batch_size, sequence_length, num_channels)` 형식과 다릅니다.
+
+## 리소스 [[resources]]
+
+Swin Transformer의 사용을 도울 수 있는 Hugging Face 및 커뮤니티(🌎로 표시)의 공식 자료 목록입니다.
+
+
+
+
+## SwinModel [[transformers.SwinModel]]
+
+[[autodoc]] SwinModel
+ - forward
+
+## SwinForMaskedImageModeling [[transformers.SwinForMaskedImageModeling]]
+
+[[autodoc]] SwinForMaskedImageModeling
+ - forward
+
+## SwinForImageClassification [[transformers.SwinForImageClassification]]
+
+[[autodoc]] transformers.SwinForImageClassification
+ - forward
+
+
+
+
+## TFSwinModel [[transformers.TFSwinModel]]
+
+[[autodoc]] TFSwinModel
+ - call
+
+## TFSwinForMaskedImageModeling [[transformers.TFSwinForMaskedImageModeling]]
+
+[[autodoc]] TFSwinForMaskedImageModeling
+ - call
+
+## TFSwinForImageClassification [[transformers.TFSwinForImageClassification]]
+
+[[autodoc]] transformers.TFSwinForImageClassification
+ - call
+
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/swin2sr.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/swin2sr.md
new file mode 100644
index 0000000000000000000000000000000000000000..931298b9593c632790f7c1e12183ed1795051f77
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/swin2sr.md
@@ -0,0 +1,59 @@
+
+
+# Swin2SR [[swin2sr]]
+
+## 개요 [[overview]]
+
+Swin2SR 모델은 Marcos V. Conde, Ui-Jin Choi, Maxime Burchi, Radu Timofte가 제안한 논문 [Swin2SR: SwinV2 Transformer for Compressed Image Super-Resolution and Restoration](https://arxiv.org/abs/2209.11345)에서 소개되었습니다.
+Swin2SR은 [SwinIR](https://github.com/JingyunLiang/SwinIR/) 모델을 개선하고자 [Swin Transformer v2](swinv2) 레이어를 도입함으로써, 훈련 불안정성, 사전 훈련과 미세 조정 간의 해상도 차이, 그리고 데이터 의존성 문제를 완화시킵니다.
+
+논문의 초록은 다음과 같습니다:
+
+*압축은 스트리밍 서비스, 가상 현실, 비디오 게임과 같은 대역폭이 제한된 시스템을 통해 이미지와 영상을 효율적으로 전송하고 저장하는 데 중요한 역할을 합니다. 하지만 압축은 필연적으로 원본 정보의 손실과 아티팩트를 초래하며, 이는 시각적 품질을 심각하게 저하시킬 수 있습니다. 이러한 이유로, 압축된 이미지의 품질 향상은 활발한 연구 주제가 되고 있습니다. 현재 대부분의 최첨단 이미지 복원 방법은 합성곱 신경망을 기반으로 하지만, SwinIR과 같은 트랜스포머 기반 방법들도 이 작업에서 인상적인 성능을 보여주고 있습니다. 이번 논문에서는 Swin Transformer V2를 사용해 SwinIR을 개선하여 이미지 초해상도 작업, 특히 압축된 입력 시나리오에서 성능을 향상시키고자 합니다. 이 방법을 통해 트랜스포머 비전 모델을 훈련할 때 발생하는 주요 문제들, 예를 들어 훈련 불안정성, 사전 훈련과 미세 조정 간 해상도 차이, 그리고 데이터 의존성을 해결할 수 있습니다. 우리는 JPEG 압축 아티팩트 제거, 이미지 초해상도(클래식 및 경량), 그리고 압축된 이미지 초해상도라는 세 가지 대표적인 작업에서 실험을 수행했습니다. 실험 결과, 우리의 방법인 Swin2SR은 SwinIR의 훈련 수렴성과 성능을 향상시킬 수 있으며, "AIM 2022 Challenge on Super-Resolution of Compressed Image and Video"에서 상위 5위 솔루션으로 선정되었습니다.*
+
+ Swin2SR 아키텍처. 원본 논문 에서 발췌.
+
+이 모델은 [nielsr](https://huggingface.co/nielsr)가 기여하였습니다.
+원본 코드는 [여기](https://github.com/mv-lab/swin2sr)에서 확인할 수 있습니다.
+
+## 리소스 [[resources]]
+
+Swin2SR demo notebook은 [여기](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Swin2SR)에서 확인할 수 있습니다.
+
+SwinSR을 활용한 image super-resolution demo space는 [여기](https://huggingface.co/spaces/jjourney1125/swin2sr)에서 확인할 수 있습니다.
+
+## Swin2SRImageProcessor [[transformers.Swin2SRImageProcessor]]
+
+[[autodoc]] Swin2SRImageProcessor
+ - preprocess
+
+## Swin2SRConfig [[transformers.Swin2SRConfig]]
+
+[[autodoc]] Swin2SRConfig
+
+## Swin2SRModel [[transformers.Swin2SRModel]]
+
+[[autodoc]] Swin2SRModel
+ - forward
+
+## Swin2SRForImageSuperResolution [[transformers.Swin2SRForImageSuperResolution]]
+
+[[autodoc]] Swin2SRForImageSuperResolution
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/swinv2.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/swinv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..3bc420a292ad7bfd80791aafa6f4ecb40bdd4242
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/swinv2.md
@@ -0,0 +1,63 @@
+
+
+# Swin Transformer V2 [[swin-transformer-v2]]
+
+## 개요 [[overview]]
+
+Swin Transformer V2는 Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo가 제안한 논문 [Swin Transformer V2: Scaling Up Capacity and Resolution](https://arxiv.org/abs/2111.09883)에서 소개되었습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*대규모 NLP 모델들은 언어 작업에서의 성능을 크게 향상하며, 성능이 포화하는 징후를 보이지 않습니다. 또한, 사람과 유사한 few-shot 학습 능력을 보여줍니다. 이 논문은 대규모 모델을 컴퓨터 비전 분야에서 탐구하고자 합니다. 대형 비전 모델을 훈련하고 적용하는 데 있어 세 가지 주요 문제를 다룹니다: 훈련 불안정성, 사전 학습과 파인튜닝 간의 해상도 차이, 그리고 레이블이 달린 데이터에 대한 높은 요구입니다. 세 가지 주요 기법을 제안합니다: 1) 훈련 안정성을 개선하기 위한 residual-post-norm 방법과 cosine attention의 결합; 2) 저해상도 이미지로 사전 학습된 모델을 고해상도 입력으로 전이할 수 있는 log-spaced continuous position bias 방법; 3) 레이블이 달린 방대한 이미지의 필요성을 줄이기 위한 self-supervised 사전 학습 방법인 SimMIM입니다. 이러한 기법들을 통해 30억 개의 파라미터를 가진 Swin Transformer V2 모델을 성공적으로 훈련하였으며, 이는 현재까지 가장 크고 고밀도의 비전 모델로, 최대 1,536×1,536 해상도의 이미지를 다룰 수 있습니다. 이 모델은 ImageNet-V2 이미지 분류, COCO 객체 탐지, ADE20K 의미론적 분할, Kinetics-400 비디오 행동 분류 등 네 가지 대표적인 비전 작업에서 새로운 성능 기록을 세웠습니다. 또한, 우리의 훈련은 Google의 billion-level 비전 모델과 비교해 40배 적은 레이블이 달린 데이터와 40배 적은 훈련 시간으로 이루어졌다는 점에서 훨씬 더 효율적입니다.*
+
+이 모델은 [nandwalritik](https://huggingface.co/nandwalritik)이 기여하였습니다.
+원본 코드는 [여기](https://github.com/microsoft/Swin-Transformer)에서 확인할 수 있습니다.
+
+## 리소스 [[resources]]
+
+Swin Transformer v2의 사용을 도울 수 있는 Hugging Face 및 커뮤니티(🌎로 표시)의 공식 자료 목록입니다.
+
+
+
+
+
+이 모델은 유지 보수 모드로만 운영되며, 코드를 변경하는 새로운 PR(Pull Request)은 받지 않습니다.
+이 모델을 실행하는 데 문제가 발생한다면, 이 모델을 지원하는 마지막 버전인 v4.30.0를 다시 설치해 주세요. 다음 명령어를 실행하여 재설치할 수 있습니다: `pip install -U transformers==4.30.0`.
+
+
+
+## 개요[[overview]]
+
+Trajectory Transformer 모델은 Michael Janner, Qiyang Li, Sergey Levine이 제안한 [하나의 커다란 시퀀스 모델링 문제로서의 오프라인 강화학습](https://arxiv.org/abs/2106.02039)라는 논문에서 소개되었습니다.
+
+해당 논문의 초록입니다:
+
+*강화학습(RL)은 일반적으로 마르코프 속성을 활용하여 시간에 따라 문제를 인수분해하면서 정적 정책이나 단일 단계 모델을 추정하는 데 중점을 둡니다. 하지만 우리는 RL을 높은 보상 시퀀스로 이어지는 행동 시퀀스를 생성하는 것을 목표로 하는 일반적인 시퀀스 모델링 문제로 볼 수도 있습니다. 이러한 관점에서, 자연어 처리와 같은 다른 도메인에서 잘 작동하는 고용량 시퀀스 예측 모델이 RL 문제에도 효과적인 해결책을 제공할 수 있는지 고려해 볼 만합니다. 이를 위해 우리는 RL을 시퀀스 모델링의 도구로 어떻게 다룰 수 있는지 탐구하며, 트랜스포머 아키텍처를 사용하여 궤적에 대한 분포를 모델링하고 빔 서치를 계획 알고리즘으로 재활용합니다. RL을 시퀀스 모델링 문제로 프레임화하면 다양한 설계 결정이 단순화되어, 오프라인 RL 알고리즘에서 흔히 볼 수 있는 많은 구성 요소를 제거할 수 있습니다. 우리는 이 접근 방식의 유연성을 장기 동역학 예측, 모방 학습, 목표 조건부 RL, 오프라인 RL에 걸쳐 입증합니다. 더 나아가, 이 접근 방식을 기존의 모델 프리 알고리즘과 결합하여 희소 보상, 장기 과제에서 최신 계획기(planner)를 얻을 수 있음을 보여줍니다.*
+
+이 모델은 [CarlCochet](https://huggingface.co/CarlCochet)에 의해 기여되었습니다.
+원본 코드는 [이곳](https://github.com/jannerm/trajectory-transformer)에서 확인할 수 있습니다.
+
+## 사용 팁[[usage-tips]]
+
+이 트랜스포머는 심층 강화학습에 사용됩니다. 사용하려면 이전의 모든 타임스텝에서의 행동, 상태, 보상으로부터 시퀀스를 생성해야 합니다. 이 모델은 이 모든 요소를 함께 하나의 큰 시퀀스(궤적)로 취급합니다.
+
+## TrajectoryTransformerConfig[[transformers.TrajectoryTransformerConfig]]
+
+[[autodoc]] TrajectoryTransformerConfig
+
+## TrajectoryTransformerModel[[transformers.TrajectoryTransformerModel]]
+
+[[autodoc]] TrajectoryTransformerModel
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/vit.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/vit.md
new file mode 100644
index 0000000000000000000000000000000000000000..5f3eb3342718b14d05a4d908f405eac1c67a33e1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/vit.md
@@ -0,0 +1,172 @@
+
+
+# Vision Transformer (ViT) [[vision-transformer-vit]]
+
+## 개요 [[overview]]
+
+Vision Transformer (ViT) 모델은 Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby가 제안한 논문 [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929)에서 소개되었습니다. 이는 Transformer 인코더를 ImageNet에서 성공적으로 훈련시킨 첫 번째 논문으로, 기존의 잘 알려진 합성곱 신경망(CNN) 구조와 비교해 매우 우수한 결과를 달성했습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*Transformer 아키텍처는 자연어 처리 작업에서 사실상 표준으로 자리 잡았으나, 컴퓨터 비전 분야에서의 적용은 여전히 제한적입니다. 비전에서 어텐션 메커니즘은 종종 합성곱 신경망(CNN)과 결합하여 사용되거나, 전체 구조를 유지하면서 합성곱 신경망의 특정 구성 요소를 대체하는 데 사용됩니다. 우리는 이러한 CNN 의존성이 필요하지 않으며, 이미지 패치를 순차적으로 입력받는 순수한 Transformer가 이미지 분류 작업에서 매우 우수한 성능을 발휘할 수 있음을 보여줍니다. 대규모 데이터로 사전 학습된 후, ImageNet, CIFAR-100, VTAB 등 다양한 중소형 이미지 인식 벤치마크에 적용하면 Vision Transformer(ViT)는 최신 합성곱 신경망과 비교해 매우 우수한 성능을 발휘하면서도 훈련에 필요한 계산 자원을 상당히 줄일 수 있습니다.*
+
+ ViT 아키텍처. 원본 논문 에서 발췌.
+
+원래의 Vision Transformer에 이어, 여러 후속 연구들이 진행되었습니다:
+
+
+- [DeiT](deit) (Data-efficient Image Transformers) (Facebook AI 개발). DeiT 모델은 distilled vision transformers입니다.
+ DeiT의 저자들은 더 효율적으로 훈련된 ViT 모델도 공개했으며, 이는 [`ViTModel`] 또는 [`ViTForImageClassification`]에 바로 사용할 수 있습니다. 여기에는 3가지 크기로 4개의 변형이 제공됩니다: *facebook/deit-tiny-patch16-224*, *facebook/deit-small-patch16-224*, *facebook/deit-base-patch16-224* and *facebook/deit-base-patch16-384*. 그리고 모델에 이미지를 준비하려면 [`DeiTImageProcessor`]를 사용해야 한다는 점에 유의하십시오.
+
+- [BEiT](beit) (BERT pre-training of Image Transformers) (Microsoft Research 개발). BEiT 모델은 BERT (masked image modeling)에 영감을 받고 VQ-VAE에 기반한 self-supervised 방법을 이용하여 supervised pre-trained vision transformers보다 더 우수한 성능을 보입니다.
+
+- DINO (Vision Transformers의 self-supervised 훈련을 위한 방법) (Facebook AI 개발). DINO 방법으로 훈련된 Vision Transformer는 학습되지 않은 상태에서도 객체를 분할할 수 있는 합성곱 신경망에서는 볼 수 없는 매우 흥미로운 능력을 보여줍니다. DINO 체크포인트는 [hub](https://huggingface.co/models?other=dino)에서 찾을 수 있습니다.
+
+- [MAE](vit_mae) (Masked Autoencoders) (Facebook AI 개발). Vision Transformer를 비대칭 인코더-디코더 아키텍처를 사용하여 마스크된 패치의 높은 비율(75%)에서 픽셀 값을 재구성하도록 사전 학습함으로써, 저자들은 이 간단한 방법이 미세 조정 후 supervised 방식의 사전 학습을 능가한다는 것을 보여주었습니다.
+
+이 모델은 [nielsr](https://huggingface.co/nielsr)에 의해 기여되었습니다. 원본 코드(JAX로 작성됨)은 [여기](https://github.com/google-research/vision_transformer)에서 확인할 수 있습니다.
+
+
+참고로, 우리는 Ross Wightman의 [timm 라이브러리](https://github.com/rwightman/pytorch-image-models)에서 JAX에서 PyTorch로 변환된 가중치를 다시 변환했습니다. 모든 공로는 그에게 돌립니다!
+
+## 사용 팁 [[usage-tips]]
+
+- Transformer 인코더에 이미지를 입력하기 위해, 각 이미지는 고정 크기의 겹치지 않는 패치들로 분할된 후 선형 임베딩됩니다. 전체 이미지를 대표하는 [CLS] 토큰이 추가되어, 분류에 사용할 수 있습니다. 저자들은 또한 절대 위치 임베딩을 추가하여, 결과적으로 생성된 벡터 시퀀스를 표준 Transformer 인코더에 입력합니다.
+- Vision Transformer는 모든 이미지가 동일한 크기(해상도)여야 하므로, [ViTImageProcessor]를 사용하여 이미지를 모델에 맞게 리사이즈(또는 리스케일)하고 정규화할 수 있습니다.
+- 사전 학습이나 미세 조정 시 사용된 패치 해상도와 이미지 해상도는 각 체크포인트의 이름에 반영됩니다. 예를 들어, `google/vit-base-patch16-224`는 패치 해상도가 16x16이고 미세 조정 해상도가 224x224인 기본 크기 아키텍처를 나타냅니다. 모든 체크포인트는 [hub](https://huggingface.co/models?search=vit)에서 확인할 수 있습니다.
+- 사용할 수 있는 체크포인트는 (1) [ImageNet-21k](http://www.image-net.org/) (1,400만 개의 이미지와 21,000개의 클래스)에서만 사전 학습되었거나, 또는 (2) [ImageNet](http://www.image-net.org/challenges/LSVRC/2012/) (ILSVRC 2012, 130만 개의 이미지와 1,000개의 클래스)에서 추가로 미세 조정된 경우입니다.
+- Vision Transformer는 224x224 해상도로 사전 학습되었습니다. 미세 조정 시, 사전 학습보다 더 높은 해상도를 사용하는 것이 유리한 경우가 많습니다 ([(Touvron et al., 2019)](https://arxiv.org/abs/1906.06423), [(Kolesnikovet al., 2020)](https://arxiv.org/abs/1912.11370). 더 높은 해상도로 미세 조정하기 위해, 저자들은 원본 이미지에서의 위치에 따라 사전 학습된 위치 임베딩의 2D 보간(interpolation)을 수행합니다.
+- 최고의 결과는 supervised 방식의 사전 학습에서 얻어졌으며, 이는 NLP에서는 해당되지 않는 경우가 많습니다. 저자들은 마스크된 패치 예측(마스크된 언어 모델링에서 영감을 받은 self-supervised 사전 학습 목표)을 사용한 실험도 수행했습니다. 이 접근 방식으로 더 작은 ViT-B/16 모델은 ImageNet에서 79.9%의 정확도를 달성하였으며, 이는 처음부터 학습한 것보다 2% 개선된 결과이지만, 여전히 supervised 사전 학습보다 4% 낮습니다.
+
+### Scaled Dot Product Attention (SDPA) 사용하기 [[using-scaled-dot-product-attention-sdpa]]
+
+PyTorch는 `torch.nn.functional`의 일부로서 native scaled dot-product attention (SDPA) 연산자를 포함하고 있습니다. 이 함수는 입력 및 사용 중인 하드웨어에 따라 여러 구현 방식을 적용할 수 있습니다.자세한 내용은 [공식 문서](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)나 [GPU 추론](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention) 페이지를 참조하십시오.
+
+SDPA는 `torch>=2.1.1`에서 구현이 가능한 경우 기본적으로 사용되지만, `from_pretrained()`에서 `attn_implementation="sdpa"`로 설정하여 SDPA를 명시적으로 요청할 수도 있습니다.
+
+```
+from transformers import ViTForImageClassification
+model = ViTForImageClassification.from_pretrained("google/vit-base-patch16-224", attn_implementation="sdpa", torch_dtype=torch.float16)
+...
+```
+
+최적의 속도 향상을 위해 모델을 반정밀도(예: `torch.float16` 또는 `torch.bfloat16`)로 로드하는 것을 권장합니다.
+
+로컬 벤치마크(A100-40GB, PyTorch 2.3.0, OS Ubuntu 22.04)에서 `float32`와 `google/vit-base-patch16-224` 모델을 사용한 추론 시, 다음과 같은 속도 향상을 확인했습니다.
+
+| Batch size | Average inference time (ms), eager mode | Average inference time (ms), sdpa model | Speed up, Sdpa / Eager (x) |
+|--------------|-------------------------------------------|-------------------------------------------|------------------------------|
+| 1 | 7 | 6 | 1.17 |
+| 2 | 8 | 6 | 1.33 |
+| 4 | 8 | 6 | 1.33 |
+| 8 | 8 | 6 | 1.33 |
+
+## 리소스 [[resources]]
+
+ViT의 추론 및 커스텀 데이터에 대한 미세 조정과 관련된 데모 노트북은 [여기](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/VisionTransformer)에서 확인할 수 있습니다. Hugging Face에서 공식적으로 제공하는 자료와 커뮤니티(🌎로 표시된) 자료 목록은 ViT를 시작하는 데 도움이 될 것입니다. 이 목록에 포함될 자료를 제출하고 싶다면 Pull Request를 열어 주시면 검토하겠습니다. 새로운 내용을 설명하는 자료가 가장 이상적이며, 기존 자료를 중복하지 않도록 해주십시오.
+
+`ViTForImageClassification` 은 다음에서 지원됩니다:
+
+
+
+## ViTModel [[transformers.ViTModel]]
+
+[[autodoc]] ViTModel
+ - forward
+
+## ViTForMaskedImageModeling [[transformers.ViTForMaskedImageModeling]]
+
+[[autodoc]] ViTForMaskedImageModeling
+ - forward
+
+## ViTForImageClassification [[transformers.ViTForImageClassification]]
+
+[[autodoc]] ViTForImageClassification
+ - forward
+
+
+
+
+## TFViTModel [[transformers.TFViTModel]]
+
+[[autodoc]] TFViTModel
+ - call
+
+## TFViTForImageClassification [[transformers.TFViTForImageClassification]]
+
+[[autodoc]] TFViTForImageClassification
+ - call
+
+
+
+
+## FlaxVitModel [[transformers.FlaxViTModel]]
+
+[[autodoc]] FlaxViTModel
+ - __call__
+
+## FlaxViTForImageClassification [[transformers.FlaxViTForImageClassification]]
+
+[[autodoc]] FlaxViTForImageClassification
+ - __call__
+
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/vivit.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/vivit.md
new file mode 100644
index 0000000000000000000000000000000000000000..c9eee17cb20afc7e808423a4af02f99ec3fc2db9
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/vivit.md
@@ -0,0 +1,42 @@
+
+
+# Video Vision Transformer (ViViT) [[video-vision-transformer-vivit]]
+
+## 개요 [[overview]]
+
+Vivit 모델은 Anurag Arnab, Mostafa Dehghani, Georg Heigold, Chen Sun, Mario Lučić, Cordelia Schmid가 제안한 논문 [ViViT: A Video Vision Transformer](https://arxiv.org/abs/2103.15691)에서 소개되었습니다. 이 논문은 비디오 이해를 위한 pure-transformer 기반의 모델 집합 중에서 최초로 성공한 모델 중 하나를 소개합니다.
+
+논문의 초록은 다음과 같습니다:
+
+*우리는 이미지 분류에서 최근 성공을 거둔 순수 트랜스포머 기반 모델을 바탕으로 비디오 분류를 위한 모델을 제안합니다. 본 모델은 입력 비디오로부터 시공간 토큰을 추출한 후, 이를 일련의 트랜스포머 레이어로 인코딩합니다. 비디오에서 발생하는 긴 토큰 시퀀스를 처리하기 위해, 입력의 공간 및 시간 차원을 분리하는 여러 효율적인 모델 변형을 제안합니다. 트랜스포머 기반 모델은 대규모 학습 데이터셋에서만 효과적이라는 것이 일반적이지만, 우리는 학습 중 모델을 효과적으로 정규화하고, 사전 학습된 이미지 모델을 활용함으로써 상대적으로 작은 데이터셋에서도 학습할 수 있는 방법을 보여줍니다. 또한, 철저한 소거(ablation) 연구를 수행하고 Kinetics 400 및 600, Epic Kitchens, Something-Something v2, Moments in Time을 포함한 여러 비디오 분류 벤치마크에서 최첨단 성과를 달성하여, 기존의 3D 합성곱 신경망 기반 방법들을 능가합니다.*
+
+이 모델은 [jegormeister](https://huggingface.co/jegormeister)가 기여하였습니다. 원본 코드(JAX로 작성됨)는 [여기](https://github.com/google-research/scenic/tree/main/scenic/projects/vivit)에서 확인할 수 있습니다.
+
+## VivitConfig [[transformers.VivitConfig]]
+
+[[autodoc]] VivitConfig
+
+## VivitImageProcessor [[transformers.VivitImageProcessor]]
+
+[[autodoc]] VivitImageProcessor
+ - preprocess
+
+## VivitModel [[transformers.VivitModel]]
+
+[[autodoc]] VivitModel
+ - forward
+
+## VivitForVideoClassification [[transformers.VivitForVideoClassification]]
+
+[[autodoc]] transformers.VivitForVideoClassification
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/whisper.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/whisper.md
new file mode 100644
index 0000000000000000000000000000000000000000..f48bae1e60f5d0d7ba7ffe7c69b26bca837f0fa9
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/whisper.md
@@ -0,0 +1,128 @@
+
+
+# Whisper [[whisper]]
+
+## 개요 [[overview]]
+
+Whisper 모델은 Alec Radford, Jong Wook Kim, Tao Xu, Greg Brockman, Christine McLeavey, Ilya Sutskever에 의해 [Robust Speech Recognition via Large-Scale Weak Supervision](https://cdn.openai.com/papers/whisper.pdf)에서 제안되었습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*우리는 인터넷에서 대량의 오디오를 글로 옮긴 것을 예측하도록 간단히 훈련된 음성 처리 시스템의 성능을 연구합니다. 68만 시간의 다국어 및 다중 작업 지도(multitask supervision)에 확장했을 때, 결과 모델은 표준 벤치마크에 잘 일반화되며, 미세 조정이 필요 없는 제로샷 전송 설정에서 이전의 완전히 지도된(fully-supervised) 결과와 경쟁할 수 있는 경우가 많습니다. 사람과 비교하면, 이 모델은 사람의 정확도와 견고성에 근접합니다. 우리는 강력한 음성 처리를 위한 추가 작업의 기반이 될 모델과 추론 코드를 공개합니다.*
+
+
+
+팁:
+
+- 이 모델은 일반적으로 별도의 미세 조정 없이도 잘 작동합니다.
+- 아키텍처는 고전적인 인코더-디코더 아키텍처를 따르기 때문에, 추론을 위해 [`~generation.GenerationMixin.generate`] 함수를 사용합니다.
+- 현재 추론은 짧은 형식에만 구현되어 있으며, 오디오는 30초 미만의 세그먼트로 미리 분할되어야 합니다. 타임스탬프를 포함한 긴 형식에 대한 추론은 향후 릴리스에서 구현될 예정입니다.
+- [`WhisperProcessor`]를 사용하여 모델에 사용할 오디오를 준비하고, 예측된 ID를 텍스트로 디코딩할 수 있습니다.
+
+- 모델과 프로세서를 변환하려면 다음을 사용하는 것이 좋습니다:
+
+```bash
+python src/transformers/models/whisper/convert_openai_to_hf.py --checkpoint_path "" --pytorch_dump_folder_path "Arthur/whisper-3" --convert_preprocessor True
+```
+스크립트는 OpenAI 체크포인트에서 필요한 모든 매개변수를 자동으로 결정합니다. OpenAI 변환을 수행하려면 `tiktoken` 라이브러리를 설치해야 합니다.
+라이브러리를 설치해야 OpenAI 토큰화기를 `tokenizers` 버전으로 변환할 수 있습니다.
+
+이 모델은 [Arthur Zucker](https://huggingface.co/ArthurZ)에 의해 제공되었습니다. 이 모델의 Tensorflow 버전은 [amyeroberts](https://huggingface.co/amyeroberts)에 의해 제공되었습니다.
+원본 코드는 [여기](https://github.com/openai/whisper)에서 찾을 수 있습니다.
+
+
+
+## WhisperConfig [[whisperconfig]]
+
+[[autodoc]] WhisperConfig
+
+## WhisperTokenizer [[whispertokenizer]]
+
+[[autodoc]] WhisperTokenizer
+ - set_prefix_tokens
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## WhisperTokenizerFast [[whispertokenizerfast]]
+
+[[autodoc]] WhisperTokenizerFast
+ - set_prefix_tokens
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## WhisperFeatureExtractor [[whisperfeatureextractor]]
+
+[[autodoc]] WhisperFeatureExtractor
+ - __call__
+
+## WhisperProcessor [[whisperprocessor]]
+
+[[autodoc]] WhisperProcessor
+ - __call__
+ - from_pretrained
+ - save_pretrained
+ - batch_decode
+ - decode
+
+## WhisperModel [[whispermodel]]
+
+[[autodoc]] WhisperModel
+ - forward
+ - _mask_input_features
+
+## WhisperForConditionalGeneration [[whisperforconditionalgeneration]]
+
+[[autodoc]] WhisperForConditionalGeneration
+ - forward
+
+## WhisperForAudioClassification [[whisperforaudioclassification]]
+
+[[autodoc]] WhisperForAudioClassification
+ - forward
+
+
+
+## TFWhisperModel [[tfwhispermodel]]
+
+[[autodoc]] TFWhisperModel
+ - call
+
+## TFWhisperForConditionalGeneration [[tfwhisperforconditionalgeneration]]
+
+[[autodoc]] TFWhisperForConditionalGeneration
+ - call
+
+
+## FlaxWhisperModel [[flaxwhispermodel]]
+
+[[autodoc]] FlaxWhisperModel
+ - __call__
+
+## FlaxWhisperForConditionalGeneration [[flaxwhisperforconditionalgeneration]]
+
+[[autodoc]] FlaxWhisperForConditionalGeneration
+ - __call__
+
+## FlaxWhisperForAudioClassification [[flaxwhisperforaudioclassification]]
+
+[[autodoc]] FlaxWhisperForAudioClassification
+ - __call__
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_memory_anatomy.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_memory_anatomy.md
new file mode 100644
index 0000000000000000000000000000000000000000..a5c3a0f35292af514fc7ab2efca9f765d6ee7941
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_memory_anatomy.md
@@ -0,0 +1,242 @@
+
+
+# 모델 학습 해부하기 [[model-training-anatomy]]
+
+모델 훈련 속도와 메모리 활용의 효율성을 향상시키기 위해 적용할 수 있는 성능 최적화 기술을 이해하려면 GPU가 훈련 중에 어떻게 활용되는지, 그리고 수행되는 연산에 따라 연산 강도가 어떻게 변하는지에 익숙해져야 합니다.
+
+먼저 GPU 활용과 모델 훈련 실행에 대한 예시를 살펴보겠습니다. 데모를 위해 몇몇 라이브러리를 설치해야 합니다:
+
+```bash
+pip install transformers datasets accelerate nvidia-ml-py3
+```
+
+`nvidia-ml-py3` 라이브러리는 Python 내부에서 모델의 메모리 사용량을 모니터링할 수 있게 해줍니다. 터미널의 `nvidia-smi` 명령어에 익숙할 수 있는데, 이 라이브러리는 Python에서 직접 동일한 정보에 접근할 수 있게 해줍니다.
+
+그 다음, 100과 30000 사이의 무작위 토큰 ID와 분류기를 위한 이진 레이블인 더미 데이터를 생성합니다.
+길이가 각각 512인 총 512개의 시퀀스를 가져와 PyTorch 형식의 [`~datasets.Dataset`]에 저장합니다.
+
+
+```py
+>>> import numpy as np
+>>> from datasets import Dataset
+
+
+>>> seq_len, dataset_size = 512, 512
+>>> dummy_data = {
+... "input_ids": np.random.randint(100, 30000, (dataset_size, seq_len)),
+... "labels": np.random.randint(0, 1, (dataset_size)),
+... }
+>>> ds = Dataset.from_dict(dummy_data)
+>>> ds.set_format("pt")
+```
+
+GPU 활용 및 [`Trainer`]로 실행한 훈련 과정에 대한 요약 통계를 출력하기 위해 두 개의 도우미 함수를 정의하겠습니다:
+
+```py
+>>> from pynvml import *
+
+
+>>> def print_gpu_utilization():
+... nvmlInit()
+... handle = nvmlDeviceGetHandleByIndex(0)
+... info = nvmlDeviceGetMemoryInfo(handle)
+... print(f"GPU memory occupied: {info.used//1024**2} MB.")
+
+
+>>> def print_summary(result):
+... print(f"Time: {result.metrics['train_runtime']:.2f}")
+... print(f"Samples/second: {result.metrics['train_samples_per_second']:.2f}")
+... print_gpu_utilization()
+```
+
+시작할 때 GPU 메모리가 비어 있는지 확인해 봅시다:
+
+```py
+>>> print_gpu_utilization()
+GPU memory occupied: 0 MB.
+```
+
+좋습니다. 모델을 로드하기 전에는 예상대로 GPU 메모리가 점유되지 않았습니다. 그렇지 않다면 사용자의 기기에서 GPU 메모리를 사용하는 모든 프로세스를 중단해야 합니다. 그러나 사용자는 모든 여유 GPU 메모리를 사용할 수는 없습니다. 모델이 GPU에 로드될 때 커널도 로드되므로 1-2GB의 메모리를 차지할 수 있습니다. 얼마나 되는지 확인하기 위해 GPU에 작은 텐서를 로드하여 커널이 로드되도록 트리거합니다.
+
+```py
+>>> import torch
+
+
+>>> torch.ones((1, 1)).to("cuda")
+>>> print_gpu_utilization()
+GPU memory occupied: 1343 MB.
+```
+
+커널만으로도 GPU 메모리의 1.3GB를 차지합니다. 이제 모델이 얼마나 많은 공간을 사용하는지 확인해 보겠습니다.
+
+## 모델 로드 [[load-model]]
+
+우선, `google-bert/bert-large-uncased` 모델을 로드합니다. 모델의 가중치를 직접 GPU에 로드해서 가중치만이 얼마나 많은 공간을 차지하는지 확인할 수 있습니다.
+
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("google-bert/bert-large-uncased").to("cuda")
+>>> print_gpu_utilization()
+GPU memory occupied: 2631 MB.
+```
+
+모델의 가중치만으로도 GPU 메모리를 1.3 GB 차지하는 것을 볼 수 있습니다. 정확한 숫자는 사용하는 GPU에 따라 다릅니다. 최신 GPU에서는 모델 사용 속도를 높이는 최적화된 방식으로 가중치가 로드되므로, 모델이 더 많은 공간을 차지할 수 있습니다. 이제 `nvidia-smi` CLI와 동일한 결과를 얻는지 빠르게 확인할 수 있습니다:
+
+
+```bash
+nvidia-smi
+```
+
+```bash
+Tue Jan 11 08:58:05 2022
++-----------------------------------------------------------------------------+
+| NVIDIA-SMI 460.91.03 Driver Version: 460.91.03 CUDA Version: 11.2 |
+|-------------------------------+----------------------+----------------------+
+| GPU Name Persistence-M| Bus-Id Disp.A | Volatile Uncorr. ECC |
+| Fan Temp Perf Pwr:Usage/Cap| Memory-Usage | GPU-Util Compute M. |
+| | | MIG M. |
+|===============================+======================+======================|
+| 0 Tesla V100-SXM2... On | 00000000:00:04.0 Off | 0 |
+| N/A 37C P0 39W / 300W | 2631MiB / 16160MiB | 0% Default |
+| | | N/A |
++-------------------------------+----------------------+----------------------+
+
++-----------------------------------------------------------------------------+
+| Processes: |
+| GPU GI CI PID Type Process name GPU Memory |
+| ID ID Usage |
+|=============================================================================|
+| 0 N/A N/A 3721 C ...nvs/codeparrot/bin/python 2629MiB |
++-----------------------------------------------------------------------------+
+```
+
+이전과 동일한 숫자가 출력되고 16GB 메모리를 가진 V100 GPU를 사용하고 있다는 것도 볼 수 있습니다. 그러므로 이제 모델 훈련을 시작하여 GPU 메모리 사용량이 어떻게 달라지는지 볼 수 있습니다. 우선 몇몇 표준 훈련 인수를 설정합니다:
+
+```py
+default_args = {
+ "output_dir": "tmp",
+ "eval_strategy": "steps",
+ "num_train_epochs": 1,
+ "log_level": "error",
+ "report_to": "none",
+}
+```
+
+
+
+여러 실험을 실행할 계획이라면, 실험 간에 메모리를 제대로 비우기 위해서 Python 커널을 실험 사이마다 재시작해야 합니다.
+
+
+
+## 기본 훈련에서의 메모리 활용 [[memory-utilization-at-vanilla-training]]
+
+[`Trainer`]를 사용하여, GPU 성능 최적화 기술을 사용하지 않고 배치 크기가 4인 모델을 훈련시키겠습니다:
+
+```py
+>>> from transformers import TrainingArguments, Trainer, logging
+
+>>> logging.set_verbosity_error()
+
+
+>>> training_args = TrainingArguments(per_device_train_batch_size=4, **default_args)
+>>> trainer = Trainer(model=model, args=training_args, train_dataset=ds)
+>>> result = trainer.train()
+>>> print_summary(result)
+```
+
+```
+Time: 57.82
+Samples/second: 8.86
+GPU memory occupied: 14949 MB.
+```
+
+우리는 비교적 작은 배치 크기로도 전체 GPU 메모리를 거의 다 차지하는 것을 볼 수 있습니다. 그러나 배치 크기가 클수록 모델 수렴 속도가 빨라지고 최종 성능이 향상되는 경우가 많습니다. 그래서 이상적으로는 GPU 제한이 아닌 우리 모델의 요구사항에 맞게 배치 크기를 조정하려고 합니다. 흥미롭게도 우리는 모델의 크기보다 훨씬 더 많은 메모리를 사용합니다. 왜 이런 현상이 발생하는지 조금 더 잘 이해하기 위해 모델의 연산과 메모리 요구 사항을 살펴보겠습니다.
+
+## 모델의 연산 해부하기 [[anatomy-of-models-operations]]
+
+트랜스포머 아키텍처에는 연산 강도(compute-intensity)에 따라 그룹화된 3가지 주요 연산 그룹이 있습니다.
+
+1. **텐서 축약(Tensor Contractions)**
+
+ 선형 레이어와 멀티헤드 어텐션의 구성 요소는 모두 **행렬-행렬 곱셈(matrix-matrix multiplications)**을 일괄적으로 처리합니다. 이 연산은 트랜스포머 훈련에서 가장 연산 강도가 높은 부분입니다.
+
+2. **통계 정규화(Statistical Normalizations)**
+
+ 소프트맥스와 레이어 정규화는 텐서 축약보다 연산 강도가 낮습니다. 하나 이상의 **감소 연산(reduction operations)**을 포함하며, 그 결과는 map을 통해 적용됩니다.
+
+3. **원소별 연산자(Element-wise Operators)**
+
+ 그 외 연산자들, **편향(biases), 드롭아웃(dropout), 활성화 함수(activations), 잔차 연결(residual connections)**이 여기에 해당합니다. 이 연산들은 연산 강도가 가장 낮습니다.
+
+이러한 지식은 성능 병목 현상을 분석할 때 도움이 될 수 있습니다.
+
+이 내용은 [Data Movement Is All You Need: A Case Study on Optimizing Transformers 2020](https://arxiv.org/abs/2007.00072)을 참고하였습니다.
+
+
+## 모델의 메모리 구조 [[anatomy-of-models-memory]]
+
+모델을 훈련시키는 데는 단순히 GPU에 모델을 올리는 것보다 훨씬 더 많은 메모리를 사용한다는 것을 보았습니다. 이는 훈련 중 GPU 메모리를 사용하는 많은 구성 요소가 있기 때문입니다. GPU 메모리의 구성 요소는 다음과 같습니다:
+
+1. 모델 가중치
+2. 옵티마이저 상태
+3. 그라디언트
+4. 그라디언트 계산을 위해 저장된 순방향 활성화
+5. 임시 버퍼
+6. 기능별 메모리
+
+AdamW를 사용하여 혼합 정밀도로 훈련된 일반적인 모델은 모델 파라미터당 18 바이트와 활성화 메모리가 필요합니다. 추론 단계에서는 옵티마이저와 그라디언트가 필요하지 않으므로 이들은 제외합니다. 따라서 혼합 정밀도 추론의 경우 모델 매개변수당 6 바이트와 활성화 메모리가 필요합니다.
+
+자세히 살펴보겠습니다.
+
+**모델 가중치:**
+
+- fp32 훈련의 경우 매개 변수 수 * 4 바이트
+- 혼합 정밀도 훈련의 경우 매개 변수 수 * 6 바이트 (메모리에 fp32와 fp16 두 가지 모델을 유지)
+
+**옵티마이저 상태:**
+
+- 일반 AdamW의 경우 매개 변수 수 * 8 바이트 (2가지 상태 유지)
+- [bitsandbytes](https://github.com/TimDettmers/bitsandbytes)와 같은 8비트 AdamW 옵티마이저의 경우 매개 변수 수 * 2 바이트
+- Momentum을 가진 SGD와 같은 옵티마이저의 경우 매개 변수 수 * 4 바이트 (하나의 상태만 유지)
+
+**그라디언트**
+
+- fp32 또는 혼합 정밀도 훈련의 경우 매개 변수 수 * 4 바이트 (그라디언트는 항상 fp32으로 유지됩니다.)
+
+**순방향 활성화**
+
+- 크기는 여러 요인에 따라 달라지며, 주요 요인은 시퀀스 길이, 은닉 상태의 크기 및 배치 크기입니다.
+
+순방향 및 역방향 함수에서 전달 및 반환되는 입력과 출력이 있으며, 그라디언트 계산을 위해 저장된 순방향 활성화가 있습니다.
+
+**임시 메모리**
+
+더불어 모든 종류의 임시 변수는 연산이 완료되면 곧바로 해제되지만, 그 순간에는 추가 메모리가 필요할 수 있고 OOM을 유발할 수 있습니다. 따라서 코딩할 때 이러한 임시 변수에 대해 전략적으로 생각하고 때로는 더 이상 필요 없는 임시 변수를 즉시 명시적으로 메모리에서 제거하는 것이 중요합니다.
+
+**기능별 메모리**
+
+그런 다음, 소프트웨어에는 특별한 메모리 요구 사항이 있을 수 있습니다. 예를 들어, 빔 검색을 사용하여 텍스트를 생성할 때 소프트웨어는 입력과 출력 사본을 여러 개 유지해야 합니다.
+
+**`forward` vs `backward` 실행 속도**
+
+합성곱과 선형 레이어의 경우 순방향에 비해 역방향에서는 2배의 플롭스가 필요하므로 일반적으로 2배 정도 느리게 변환됩니다(역방향의 경우 사이즈가 부자연스럽기 때문에, 때로는 더욱 느릴 수도 있습니다). 활성화는 일반적으로 대역폭이 제한되어 있으며, 일반적으로 순방향보다 역방향에서 더 많은 데이터를 읽어야 합니다. (예를 들어, 순방향 활성화 시 한 번 씩 읽고 쓰지만, 역방향 활성화에서는 순방향 gradOutput과 출력에 대해 총 두 번 읽고 gradInput에 대해 한 번 씁니다.)
+
+보다시피, GPU 메모리를 절약하거나 작업 속도를 높일 수 있는 몇 가지 방법이 있습니다.
+이제 GPU 활용과 계산 속도에 영향을 주는 것이 무엇인지를 이해했으므로, [Methods and tools for efficient training on a single GPU](perf_train_gpu_one) 문서 페이지를 참조하여 성능 최적화 기법에 대해 알아보세요.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_sharing.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_sharing.md
new file mode 100644
index 0000000000000000000000000000000000000000..3811507796627522c8e91c229b2cbbe9786eb7f0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_sharing.md
@@ -0,0 +1,232 @@
+
+
+# 모델 공유하기[[share-a-model]]
+
+지난 두 튜토리얼에서 분산 설정을 위해 PyTorch, Keras 및 🤗 Accelerate를 사용하여 모델을 미세 조정하는 방법을 보았습니다. 다음 단계는 모델을 커뮤니티와 공유하는 것입니다! Hugging Face는 인공지능의 민주화를 위해 모두에게 지식과 자원을 공개적으로 공유해야 한다고 믿습니다. 다른 사람들이 시간과 자원을 절약할 수 있도록 커뮤니티에 모델을 공유하는 것을 고려해 보세요.
+
+이 튜토리얼에서 [Model Hub](https://huggingface.co/models)에서 훈련되거나 미세 조정 모델을 공유하는 두 가지 방법에 대해 알아봅시다:
+
+- API를 통해 파일을 Hub에 푸시합니다.
+- 웹사이트를 통해 파일을 Hub로 끌어다 놓습니다.
+
+VIDEO
+
+
+
+커뮤니티에 모델을 공유하려면, [huggingface.co](https://huggingface.co/join)에 계정이 필요합니다. 기존 조직에 가입하거나 새로 만들 수도 있습니다.
+
+
+
+## 저장소 특징[[repository-features]]
+
+모델 허브의 각 저장소는 일반적인 GitHub 저장소처럼 작동합니다. 저장소는 버전 관리, 커밋 기록, 차이점 시각화 기능을 제공합니다.
+
+모델 허브에 내장된 버전 관리는 git 및 [git-lfs](https://git-lfs.github.com/)를 기반으로 합니다. 즉, 하나의 모델을 하나의 저장소로 취급하여 접근 제어 및 확장성이 향상됩니다. 버전 제어는 커밋 해시, 태그 또는 브랜치로 모델의 특정 버전을 고정하는 방법인 *revision*을 허용합니다.
+
+따라서 `revision` 매개변수를 사용하여 특정 모델 버전을 가져올 수 있습니다:
+
+```py
+>>> model = AutoModel.from_pretrained(
+... "julien-c/EsperBERTo-small", revision="4c77982" # tag name, or branch name, or commit hash
+... )
+```
+
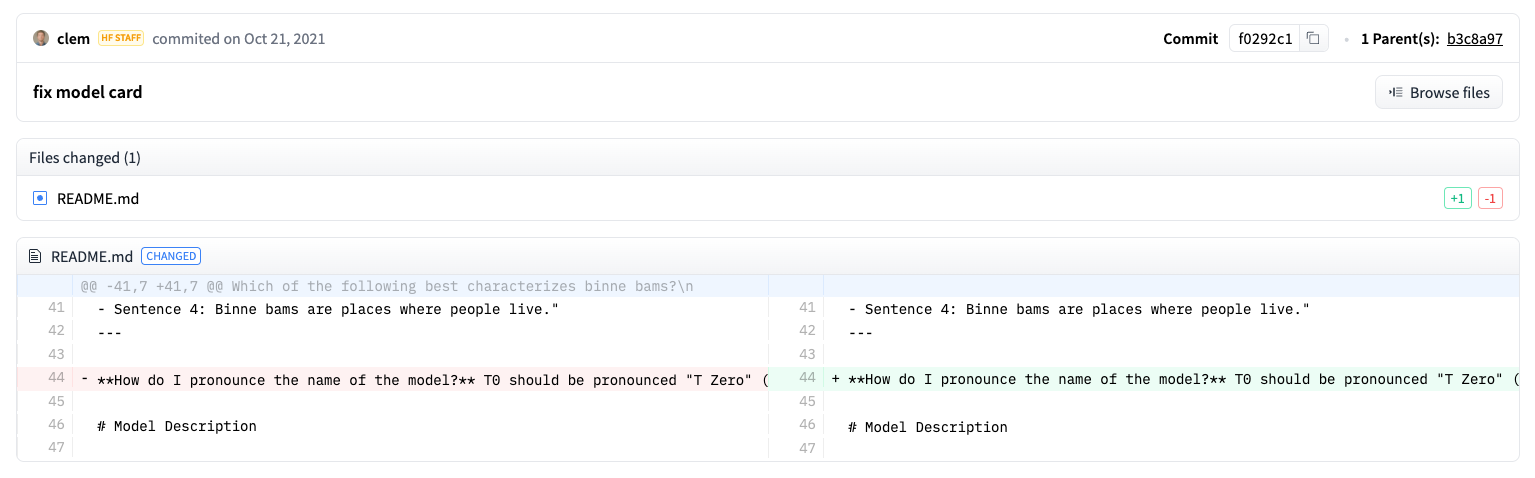
+또한 저장소에서 파일을 쉽게 편집할 수 있으며, 커밋 기록과 차이를 볼 수 있습니다:
+
+
+
+## 설정[[setup]]
+
+모델을 허브에 공유하기 전에 Hugging Face 자격 증명이 필요합니다. 터미널에 액세스할 수 있는 경우, 🤗 Transformers가 설치된 가상 환경에서 다음 명령을 실행합니다. 그러면 Hugging Face 캐시 폴더(기본적으로 `~/.cache/`)에 액세스 토큰을 저장합니다:
+
+```bash
+huggingface-cli login
+```
+
+Jupyter 또는 Colaboratory와 같은 노트북을 사용 중인 경우, [`huggingface_hub`](https://huggingface.co/docs/hub/adding-a-library) 라이브러리가 설치되었는지 확인하세요. 이 라이브러리를 사용하면 API로 허브와 상호 작용할 수 있습니다.
+
+```bash
+pip install huggingface_hub
+```
+
+그런 다음 `notebook_login`로 허브에 로그인하고, [여기](https://huggingface.co/settings/token) 링크에서 로그인할 토큰을 생성합니다:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## 프레임워크 간 모델 변환하기[[convert-a-model-for-all-frameworks]]
+
+다른 프레임워크로 작업하는 사용자가 모델을 사용할 수 있도록 하려면, PyTorch 및 TensorFlow 체크포인트를 모두 사용하여 모델을 변환하고 업로드하는 것이 좋습니다. 이 단계를 건너뛰어도 사용자는 다른 프레임워크에서 모델을 가져올 수 있지만, 🤗 Transformers가 체크포인트를 즉석에서 변환해야 하므로 속도가 느려질 수 있습니다.
+
+체크포인트를 다른 프레임워크로 변환하는 것은 쉽습니다. PyTorch 및 TensorFlow가 설치되어 있는지 확인한 다음(설치 지침은 [여기](installation) 참조) 다른 프레임워크에서 작업에 대한 특정 모델을 찾습니다.
+
+
+
+체크포인트를 TensorFlow에서 PyTorch로 변환하려면 `from_tf=True`를 지정하세요:
+
+```py
+>>> pt_model = DistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_tf=True)
+>>> pt_model.save_pretrained("path/to/awesome-name-you-picked")
+```
+
+
+체크포인트를 PyTorch에서 TensorFlow로 변환하려면 `from_pt=True`를 지정하세요:
+
+```py
+>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_pt=True)
+```
+
+그런 다음 새로운 체크포인트와 함께 새로운 TensorFlow 모델을 저장할 수 있습니다:
+
+```py
+>>> tf_model.save_pretrained("path/to/awesome-name-you-picked")
+```
+
+
+Flax에서 모델을 사용하는 경우, PyTorch에서 Flax로 체크포인트를 변환할 수도 있습니다:
+
+```py
+>>> flax_model = FlaxDistilBertForSequenceClassification.from_pretrained(
+... "path/to/awesome-name-you-picked", from_pt=True
+... )
+```
+
+
+
+## 훈련 중 모델 푸시하기[[push-a-model-during-training]]
+
+
+
+
+
+[`PushToHubCallback`]을 사용하여 모델을 허브에 공유하려면, [`PushToHubCallback`]에 다음 인수를 정의하세요:
+
+- 출력된 모델의 파일 경로
+- 토크나이저
+- `{Hub 사용자 이름}/{모델 이름}` 형식의 `hub_model_id`
+
+```py
+>>> from transformers import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="./your_model_save_path", tokenizer=tokenizer, hub_model_id="your-username/my-awesome-model"
+... )
+```
+
+[`fit`](https://keras.io/api/models/model_training_apis/)에 콜백을 추가하면, 🤗 Transformers가 훈련된 모델을 허브로 푸시합니다:
+
+```py
+>>> model.fit(tf_train_dataset, validation_data=tf_validation_dataset, epochs=3, callbacks=push_to_hub_callback)
+```
+
+
+
+## `push_to_hub` 함수 사용하기[[use-the-pushtohub-function]]
+
+모델에서 직접 `push_to_hub`를 호출하여 허브에 업로드할 수도 있습니다.
+
+`push_to_hub`에 모델 이름을 지정하세요:
+
+```py
+>>> pt_model.push_to_hub("my-awesome-model")
+```
+
+이렇게 하면 사용자 이름 아래에 모델 이름 `my-awesome-model`로 저장소가 생성됩니다. 이제 사용자는 `from_pretrained` 함수를 사용하여 모델을 가져올 수 있습니다:
+
+```py
+>>> from transformers import AutoModel
+
+>>> model = AutoModel.from_pretrained("your_username/my-awesome-model")
+```
+
+조직에 속하고 모델을 조직 이름으로 대신 푸시하려면 `repo_id`에 추가하세요:
+
+```py
+>>> pt_model.push_to_hub("my-awesome-org/my-awesome-model")
+```
+
+`push_to_hub` 함수는 모델 저장소에 다른 파일을 추가하는 데에도 사용할 수 있습니다. 예를 들어 모델 저장소에 토크나이저를 추가할 수 있습니다:
+
+```py
+>>> tokenizer.push_to_hub("my-awesome-model")
+```
+
+또는 미세 조정된 PyTorch 모델의 TensorFlow 버전을 추가할 수도 있습니다:
+
+```py
+>>> tf_model.push_to_hub("my-awesome-model")
+```
+
+이제 Hugging Face 프로필로 이동하면, 새로 생성한 모델 저장소가 표시됩니다. **Files** 탭을 클릭하면 저장소에 업로드한 모든 파일이 표시됩니다.
+
+저장소에 파일을 만들고 업로드하는 방법에 대한 자세한 내용은 허브 설명서 [여기](https://huggingface.co/docs/hub/how-to-upstream)를 참조하세요.
+
+## 웹 인터페이스로 업로드하기[[upload-with-the-web-interface]]
+
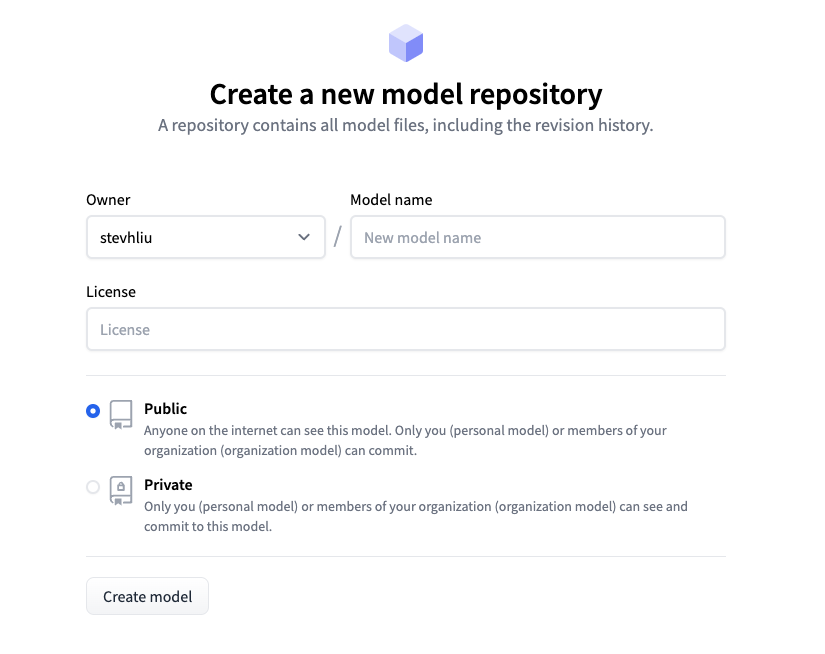
+코드 없는 접근 방식을 선호하는 사용자는 허브의 웹 인터페이스를 통해 모델을 업로드할 수 있습니다. [huggingface.co/new](https://huggingface.co/new)를 방문하여 새로운 저장소를 생성하세요:
+
+
+
+여기서 모델에 대한 몇 가지 정보를 추가하세요:
+
+- 저장소의 **소유자**를 선택합니다. 이는 사용자 또는 사용자가 속한 조직일 수 있습니다.
+- 저장소 이름이 될 모델의 이름을 선택합니다.
+- 모델이 공개인지 비공개인지 선택합니다.
+- 모델의 라이센스 사용을 지정합니다.
+
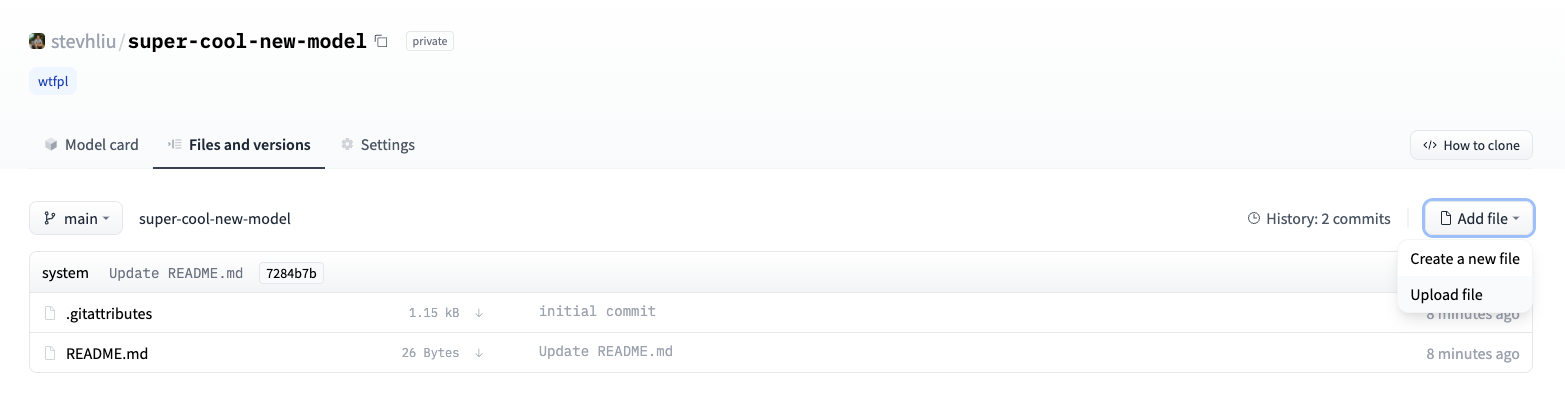
+이제 **Files** 탭을 클릭하고 **Add file** 버튼을 클릭하여 새로운 파일을 저장소에 업로드합니다. 그런 다음 업로드할 파일을 끌어다 놓고 커밋 메시지를 추가하세요.
+
+
+
+## 모델 카드 추가하기[[add-a-model-card]]
+
+사용자가 모델의 기능, 제한, 잠재적 편향 및 윤리적 고려 사항을 이해할 수 있도록 저장소에 모델 카드를 추가하세요. 모델 카드는 `README.md` 파일에 정의되어 있습니다. 다음 방법으로 모델 카드를 추가할 수 있습니다:
+
+* `README.md` 파일을 수동으로 생성하여 업로드합니다.
+* 모델 저장소에서 **Edit model card** 버튼을 클릭합니다.
+
+모델 카드에 포함할 정보 유형에 대한 좋은 예는 DistilBert [모델 카드](https://huggingface.co/distilbert/distilbert-base-uncased)를 참조하세요. 모델의 탄소 발자국이나 위젯 예시 등 `README.md` 파일에서 제어할 수 있는 다른 옵션에 대한 자세한 내용은 [여기](https://huggingface.co/docs/hub/models-cards) 문서를 참조하세요.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_summary.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..568b9425335d7f95063daca468fe67f31913a2c1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_summary.md
@@ -0,0 +1,107 @@
+
+
+# Transformer 모델군[[the-transformer-model-family]]
+
+2017년에 소개된 [기본 Transformer](https://arxiv.org/abs/1706.03762) 모델은 자연어 처리(NLP) 작업을 넘어 새롭고 흥미로운 모델들에 영감을 주었습니다. [단백질 접힘 구조 예측](https://huggingface.co/blog/deep-learning-with-proteins), [치타의 달리기 훈련](https://huggingface.co/blog/train-decision-transformers), [시계열 예측](https://huggingface.co/blog/time-series-transformers) 등을 위한 다양한 모델이 생겨났습니다. Transformer의 변형이 너무 많아서, 큰 그림을 놓치기 쉽습니다. 하지만 여기 있는 모든 모델의 공통점은 기본 Trasnformer 아키텍처를 기반으로 한다는 점입니다. 일부 모델은 인코더 또는 디코더만 사용하고, 다른 모델들은 인코더와 디코더를 모두 사용하기도 합니다. 이렇게 Transformer 모델군 내 상위 레벨에서의 차이점을 분류하고 검토하면 유용한 분류 체계를 얻을 수 있으며, 이전에 접해보지 못한 Transformer 모델들 또한 이해하는 데 도움이 될 것입니다.
+
+기본 Transformer 모델에 익숙하지 않거나 복습이 필요한 경우, Hugging Face 강의의 [트랜스포머는 어떻게 동작하나요?](https://huggingface.co/course/chapter1/4?fw=pt) 챕터를 확인하세요.
+
+
+ VIDEO
+
+
+## 컴퓨터 비전[[computer-vision]]
+
+
+
+### 합성곱 네트워크[[convolutional-network]]
+
+[Vision Transformer](https://arxiv.org/abs/2010.11929)가 확장성과 효율성을 입증하기 전까지 오랫동안 합성곱 네트워크(CNN)가 컴퓨터 비전 작업의 지배적인 패러다임이었습니다. 그럼에도 불구하고, 이동 불변성(translation invariance)과 같은 CNN의 우수한 부분이 도드라지기 때문에 몇몇 (특히 특정 과업에서의) Transformer 모델은 아키텍처에 합성곱을 통합하기도 했습니다. [ConvNeXt](model_doc/convnext)는 이런 관례를 뒤집어 CNN을 현대화하기 위해 Transformer의 디자인을 차용합니다. 예를 들면 ConvNeXt는 겹치지 않는 슬라이딩 창(sliding window)을 사용하여 이미지를 패치화하고, 더 큰 커널로 전역 수용 필드(global receptive field)를 확장시킵니다. ConvNeXt는 또한 메모리 효율을 높이고 성능을 향상시키기 위해 여러 레이어 설계를 선택하기 때문에 Transformer와 견줄만합니다!
+
+### 인코더[[cv-encoder]]
+
+[Vision Transformer(ViT)](model_doc/vit)는 합성곱 없는 컴퓨터 비전 작업의 막을 열었습니다. ViT는 표준 Transformer 인코더를 사용하지만, 가장 큰 혁신은 이미지를 처리하는 방식이었습니다. 문장을 토큰으로 분할하는 것처럼 이미지를 고정된 크기의 패치로 분할하고, 이를 사용하여 임베딩을 생성합니다. ViT는 Transformer의 효율적인 아키텍처를 활용하여 훈련에 더 적은 자원을 사용하면서도 당시 CNN에 비견하는 결과를 입증했습니다. 그리고 ViT를 뒤이어 분할(segmentation)과 같은 고밀도 비전 작업과 탐지 작업도 다룰 수 있는 다른 비전 모델이 등장했습니다.
+
+이러한 모델 중 하나가 [Swin](model_doc/swin) Transformer입니다. 이 모델은 작은 크기의 패치에서 계층적 특징 맵(CNN 👀과 같지만 ViT와는 다름)을 만들고 더 깊은 레이어의 인접 패치와 병합합니다. 어텐션(Attention)은 지역 윈도우 내에서만 계산되며, 모델이 더 잘 학습할 수 있도록 어텐션 레이어 간에 윈도우를 이동하며 연결을 생성합니다. Swin Transformer는 계층적 특징 맵을 생성할 수 있으므로, 분할(segmentation)과 탐지와 같은 고밀도 예측 작업에 적합합니다. [SegFormer](model_doc/segformer) 역시 Transformer 인코더를 사용하여 계층적 특징 맵을 구축하지만, 상단에 간단한 다층 퍼셉트론(MLP) 디코더를 추가하여 모든 특징 맵을 결합하고 예측을 수행합니다.
+
+BeIT와 ViTMAE와 같은 다른 비전 모델은 BERT의 사전훈련 목표(objective)에서 영감을 얻었습니다. [BeIT](model_doc/beit)는 *마스크드 이미지 모델링(MIM)*으로 사전훈련되며, 이미지 패치는 임의로 마스킹되고 이미지도 시각적 토큰으로 토큰화됩니다. BeIT는 마스킹된 패치에 해당하는 시각적 토큰을 예측하도록 학습됩니다. [ViTMAE](model_doc/vitmae)도 비슷한 사전훈련 목표가 있지만, 시각적 토큰 대신 픽셀을 예측해야 한다는 점이 다릅니다. 특이한 점은 이미지 패치의 75%가 마스킹되어 있다는 것입니다! 디코더는 마스킹된 토큰과 인코딩된 패치에서 픽셀을 재구성합니다. 사전훈련이 끝나면 디코더는 폐기되고 인코더는 다운스트림 작업에 사용할 준비가 됩니다.
+
+### 디코더[[cv-decoder]]
+
+대부분의 비전 모델은 인코더에 의존하여 이미지 표현을 학습하기 때문에 디코더 전용 비전 모델은 드뭅니다. 하지만 이미지 생성 등의 사례의 경우, GPT-2와 같은 텍스트 생성 모델에서 보았듯이 디코더가 가장 적합합니다. [ImageGPT](model_doc/imagegpt)는 GPT-2와 동일한 아키텍처를 사용하지만, 시퀀스의 다음 토큰을 예측하는 대신 이미지의 다음 픽셀을 예측합니다. ImageGPT는 이미지 생성 뿐만 아니라 이미지 분류를 위해 미세 조정할 수도 있습니다.
+
+### 인코더-디코더[[cv-encoder-decoder]]
+
+비전 모델은 일반적으로 인코더(백본으로도 알려짐)를 사용하여 중요한 이미지 특징을 추출한 후, 이를 Transformer 디코더로 전달합니다. [DETR](model_doc/detr)에 사전훈련된 백본이 있지만, 객체 탐지를 위해 완전한 Transformer 인코더-디코더 아키텍처도 사용합니다. 인코더는 이미지 표현을 학습하고 이를 디코더에서 객체 쿼리(각 객체 쿼리는 이미지의 영역 또는 객체에 중점을 두고 학습된 임베딩)와 결합합니다. DETR은 각 객체 쿼리에 대한 바운딩 박스 좌표와 클래스 레이블을 예측합니다.
+
+## 자연어처리[[natural-language-processing]]
+
+
+
+### 인코더[[nlp-encoder]]
+
+[BERT](model_doc/bert)는 인코더 전용 Transformer로, 다른 토큰을 보고 소위 "부정 행위"를 저지르는 걸 막기 위해 입력에서 특정 토큰을 임의로 마스킹합니다. 사전훈련의 목표는 컨텍스트를 기반으로 마스킹된 토큰을 예측하는 것입니다. 이를 통해 BERT는 왼쪽과 오른쪽 컨텍스트를 충분히 활용하여 입력에 대해 더 깊고 풍부한 표현을 학습할 수 있습니다. 그러나 BERT의 사전훈련 전략에는 여전히 개선의 여지가 남아 있었습니다. [RoBERTa](model_doc/roberta)는 더 긴 시간 동안 더 큰 배치에 대한 훈련을 포함하고, 전처리 중에 한 번만 마스킹하는 것이 아니라 각 에폭에서 토큰을 임의로 마스킹하고, 다음 문장 예측 목표를 제거하는 새로운 사전훈련 방식을 도입함으로써 이를 개선했습니다.
+
+성능 개선을 위한 전략으로 모델 크기를 키우는 것이 지배적입니다. 하지만 큰 모델을 훈련하려면 계산 비용이 많이 듭니다. 계산 비용을 줄이는 한 가지 방법은 [DistilBERT](model_doc/distilbert)와 같이 작은 모델을 사용하는 것입니다. DistilBERT는 압축 기법인 [지식 증류(knowledge distillation)](https://arxiv.org/abs/1503.02531)를 사용하여, 거의 모든 언어 이해 능력을 유지하면서 더 작은 버전의 BERT를 만듭니다.
+
+그러나 대부분의 Transformer 모델에 더 많은 매개변수를 사용하는 경향이 이어졌고, 이에 따라 훈련 효율성을 개선하는 것에 중점을 둔 새로운 모델이 등장했습니다. [ALBERT](model_doc/albert)는 두 가지 방법으로 매개변수 수를 줄여 메모리 사용량을 줄였습니다. 바로 큰 어휘를 두 개의 작은 행렬로 분리하는 것과 레이어가 매개변수를 공유하도록 하는 것입니다. [DeBERTa](model_doc/deberta)는 단어와 그 위치를 두 개의 벡터로 개별적으로 인코딩하는 분리된(disentangled) 어텐션 메커니즘을 추가했습니다. 어텐션은 단어와 위치 임베딩을 포함하는 단일 벡터 대신 이 별도의 벡터에서 계산됩니다. [Longformer](model_doc/longformer)는 특히 시퀀스 길이가 긴 문서를 처리할 때, 어텐션을 더 효율적으로 만드는 것에 중점을 두었습니다. 지역(local) 윈도우 어텐션(각 토큰 주변의 고정된 윈도우 크기에서만 계산되는 어텐션)과 전역(global) 어텐션(분류를 위해 `[CLS]`와 같은 특정 작업 토큰에만 해당)의 조합을 사용하여 전체(full) 어텐션 행렬 대신 희소(sparse) 어텐션 행렬을 생성합니다.
+
+### 디코더[[nlp-decoder]]
+
+[GPT-2](model_doc/gpt2)는 시퀀스에서 다음 단어를 예측하는 디코더 전용 Transformer입니다. 토큰을 오른쪽으로 마스킹하여 모델이 이전 토큰을 보고 "부정 행위"를 하지 못하도록 합니다. GPT-2는 방대한 텍스트에 대해 사전훈련하여 텍스트가 일부만 정확하거나 사실인 경우에도 상당히 능숙하게 텍스트를 생성할 수 있게 되었습니다. 하지만 GPT-2는 BERT가 사전훈련에서 갖는 양방향 컨텍스트가 부족하기 때문에 특정 작업에 적합하지 않았습니다. [XLNET](model_doc/xlnet)은 양방향 훈련이 가능한 permutation language modeling objective(PLM)를 사용하여 BERT와 GPT-2의 사전훈련 목표에 대한 장점을 함께 가지고 있습니다.
+
+GPT-2 이후, 언어 모델은 더욱 거대해졌고 현재는 *대규모 언어 모델(LLM)*로 알려져 있습니다. 충분히 큰 데이터 세트로 사전훈련된 LLM은 퓨샷(few-shot) 또는 제로샷(zero-shot) 학습을 수행합니다. [GPT-J](model_doc/gptj)는 6B 크기의 매개변수가 있고 400B 크기의 토큰으로 훈련된 LLM입니다. GPT-J에 이어 디코더 전용 모델군인 [OPT](model_doc/opt)가 등장했으며, 이 중 가장 큰 모델은 175B 크기이고 180B 크기의 토큰으로 훈련되었습니다. [BLOOM](model_doc/bloom)은 비슷한 시기에 출시되었으며, 이 중 가장 큰 모델은 176B 크기의 매개변수가 있고 46개의 언어와 13개의 프로그래밍 언어로 된 366B 크기의 토큰으로 훈련되었습니다.
+
+### 인코더-디코더[[nlp-encoder-decoder]]
+
+[BART](model_doc/bart)는 기본 Transformer 아키텍처를 유지하지만, 일부 텍스트 스팬(span)이 단일 `마스크` 토큰으로 대체되는 *text infilling* 변형으로 사전훈련 목표를 수정합니다. 디코더는 변형되지 않은 토큰(향후 토큰은 마스킹됨)을 예측하고 인코더의 은닉 상태를 사용하여 이 작업을 돕습니다. [Pegasus](model_doc/pegasus)는 BART와 유사하지만, Pegasus는 텍스트 스팬 대신 전체 문장을 마스킹합니다. Pegasus는 마스크드 언어 모델링 외에도 gap sentence generation(GSG)로 사전훈련됩니다. GSG는 문서에 중요한 문장 전체를 마스킹하여 `마스크` 토큰으로 대체하는 것을 목표로 합니다. 디코더는 남은 문장에서 출력을 생성해야 합니다. [T5](model_doc/t5)는 특정 접두사를 사용하여 모든 NLP 작업을 텍스트 투 텍스트 문제로 변환하는 더 특수한 모델입니다. 예를 들어, 접두사 `Summarize:`은 요약 작업을 나타냅니다. T5는 지도(GLUE 및 SuperGLUE) 훈련과 자기지도 훈련(토큰의 15%를 임의로 샘플링하여 제거)으로 사전훈련됩니다.
+
+## 오디오[[audio]]
+
+
+
+### 인코더[[audio-encoder]]
+
+[Wav2Vec2](model_doc/wav2vec2)는 Transformer 인코더를 사용하여 원본 오디오 파형(raw audio waveform)에서 직접 음성 표현을 학습합니다. 허위 음성 표현 세트에서 실제 음성 표현을 판별하는 대조 작업으로 사전훈련됩니다. [HuBERT](model_doc/hubert)는 Wav2Vec2와 유사하지만 훈련 과정이 다릅니다. 타겟 레이블이 유사한 오디오 세그먼트가 클러스터에 할당되어 은닉 단위(unit)가 되는 군집화(clustering) 단계에서 생성됩니다. 은닉 단위는 예측을 위한 임베딩에 매핑됩니다.
+
+### 인코더-디코더[[audio-encoder-decoder]]
+
+[Speech2Text](model_doc/speech_to_text)는 자동 음성 인식(ASR) 및 음성 번역을 위해 고안된 음성 모델입니다. 이 모델은 오디오 파형에서 추출한 log mel-filter bank 특징을 채택하고 자기회귀 방식으로 사전훈련하여, 전사본 또는 번역을 만듭니다. [Whisper](model_doc/whisper)은 ASR 모델이지만, 다른 많은 음성 모델과 달리 제로샷 성능을 위해 대량의 ✨ 레이블이 지정된 ✨ 오디오 전사 데이터에 대해 사전훈련됩니다. 데이터 세트의 큰 묶음에는 영어가 아닌 언어도 포함되어 있어서 자원이 적은 언어에도 Whisper를 사용할 수 있습니다. 구조적으로, Whisper는 Speech2Text와 유사합니다. 오디오 신호는 인코더에 의해 인코딩된 log-mel spectrogram으로 변환됩니다. 디코더는 인코더의 은닉 상태와 이전 토큰으로부터 자기회귀 방식으로 전사를 생성합니다.
+
+## 멀티모달[[multimodal]]
+
+
+
+### 인코더[[mm-encoder]]
+
+[VisualBERT](model_doc/visual_bert)는 BERT 이후에 출시된 비전 언어 작업을 위한 멀티모달 모델입니다. 이 모델은 BERT와 사전훈련된 객체 탐지 시스템을 결합하여 이미지 특징을 시각 임베딩으로 추출하고, 텍스트 임베딩과 함께 BERT로 전달합니다. VisualBERT는 마스킹되지 않은 텍스트와 시각 임베딩을 기반으로 마스킹된 텍스트를 예측하고, 텍스트가 이미지와 일치하는지 예측해야 합니다. ViT가 이미지 임베딩을 구하는 방식이 더 쉬웠기 때문에, ViT가 출시된 후 [ViLT](model_doc/vilt)는 아키텍처에 ViT를 채택했습니다. 이미지 임베딩은 텍스트 임베딩과 함께 처리됩니다. 여기에서, ViLT는 이미지 텍스트 매칭, 마스크드 언어 모델링, 전체 단어 마스킹을 통해 사전훈련됩니다.
+
+[CLIP](model_doc/clip)은 다른 접근 방식을 사용하여 (`이미지`, `텍스트`)의 쌍 예측을 수행합니다. (`이미지`, `텍스트`) 쌍에서의 이미지와 텍스트 임베딩 간의 유사도를 최대화하기 위해 4억 개의 (`이미지`, `텍스트`) 쌍 데이터 세트에 대해 이미지 인코더(ViT)와 텍스트 인코더(Transformer)를 함께 훈련합니다. 사전훈련 후, 자연어를 사용하여 이미지가 주어진 텍스트를 예측하거나 그 반대로 예측하도록 CLIP에 지시할 수 있습니다. [OWL-ViT](model_doc/owlvit)는 CLIP을 제로샷 객체 탐지를 위한 백본(backbone)으로 사용하여 CLIP 상에 구축됩니다. 사전훈련 후, 객체 탐지 헤드가 추가되어 (`클래스`, `바운딩 박스`) 쌍에 대한 집합(set) 예측을 수행합니다.
+
+### 인코더-디코더[[mm-encoder-decoder]]
+
+광학 문자 인식(OCR)은 이미지를 이해하고 텍스트를 생성하기 위해 다양한 구성 요소를 필요로 하는 전통적인 텍스트 인식 작업입니다. [TrOCR](model_doc/trocr)은 종단간(end-to-end) Transformer를 사용하여 이 프로세스를 간소화합니다. 인코더는 이미지 이해를 위한 ViT 방식의 모델이며 이미지를 고정된 크기의 패치로 처리합니다. 디코더는 인코더의 은닉 상태를 받아서 자기회귀 방식으로 텍스트를 생성합니다. [Donut](model_doc/donut)은 OCR 기반 접근 방식에 의존하지 않는 더 일반적인 시각 문서 이해 모델입니다. 이 모델은 Swin Transformer를 인코더로, 다국어 BART를 디코더로 사용합니다. Donut은 이미지와 텍스트 주석을 기반으로 다음 단어를 예측하여 텍스트를 읽도록 사전훈련됩니다. 디코더는 프롬프트가 주어지면 토큰 시퀀스를 생성합니다. 프롬프트는 각 다운스트림 작업에 대한 특수 토큰으로 표현됩니다. 예를 들어, 문서 파싱(parsing)에는 인코더의 은닉 상태와 결합되어 문서를 정형 출력 형식(JSON)으로 파싱하는 특수 `파싱` 토큰이 있습니다.
+
+## 강화 학습[[reinforcement-learning]]
+
+
+
+### 디코더[[rl-decoder]]
+
+Decision 및 Trajectory Transformer는 상태(state), 행동(action), 보상(reward)을 시퀀스 모델링 문제로 표현합니다. [Decision Transformer](model_doc/decision_transformer)는 기대 보상(returns-to-go), 과거 상태 및 행동을 기반으로 미래의 원하는 수익(return)으로 이어지는 일련의 행동을 생성합니다. 마지막 *K* 시간 스텝(timestep)에 대해, 세 가지 모달리티는 각각 토큰 임베딩으로 변환되고 GPT와 같은 모델에 의해 처리되어 미래의 액션 토큰을 예측합니다. [Trajectory Transformer](model_doc/trajectory_transformer)도 상태, 행동, 보상을 토큰화하여 GPT 아키텍처로 처리합니다. 보상 조건에 중점을 둔 Decision Transformer와 달리 Trajectory Transformer는 빔 서치(beam search)로 미래 행동을 생성합니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/modular_transformers.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/modular_transformers.md
new file mode 100644
index 0000000000000000000000000000000000000000..096dd4f13a9889dad2c3ab0a6ca3c1308ab952b2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/modular_transformers.md
@@ -0,0 +1,96 @@
+# 모듈식 트랜스포머 [[modular-transformers]]
+
+`transformers`는 opinionated(자기 의견이 강한) 프레임워크이며, 우리의 철학은 다음의 [개념 가이드](./philosophy)에 정의되어 있습니다.
+
+이 철학의 핵심은 라이브러리의 [단일 모델, 단일 파일](https://huggingface.co/blog/transformers-design-philosophy) 측면에서 잘 나타납니다. 이 구성 요소의 단점은 파일 간에 구성 요소의 상속과 임포트 가능성을 제한한다는 것입니다.
+
+그 결과, 모델 구성 요소가 여러 파일에 걸쳐 반복되는 경향이 있습니다. `transformers`에는 모델 수만큼 많은 어텐션 레이어가 정의되어 있으며, 그 중 상당수는 서로 동일합니다. 안타깝게도, 수정과 변경 사항이 코드의 특정 부분에 적용되면서 독립적인 구현들이 서로 분기되는 경향이 있습니다.
+
+이 문제를 적절히 해결하기 위해, 우리는 라이브러리 전체에 "복사본"의 개념을 도입했습니다. 코드가 다른 코드의 복사본임을 나타내는 주석을 추가함으로써, CI 및 로컬 명령을 통해 복사본이 분기되지 않도록 강제할 수 있습니다. 그러나 복잡성이 낮더라도 이는 종종 매우 번거로운 작업입니다.
+
+마지막으로, 이 방식은 우리가 줄이고자 하는 상당한 오버헤드를 모델 기여 과정에 추가하게 됩니다. 이 접근 방식은 종종 모델 기여에 모델링 코드(~1,000줄), 프로세서(~500줄), 테스트, 문서 등을 추가해야 합니다. 모델 기여 PR은 대부분 3,000~5,000줄 이상의 코드를 추가하며, 이 중 많은 부분이 보일러플레이트(boilerplate) 코드입니다.
+
+이는 기여의 장벽을 높이며, 모듈식 트랜스포머를 통해 우리는 이러한 장벽을 훨씬 더 수용 가능한 수준으로 낮추고자 합니다.
+
+## 무엇인가요 [[what-is-it]]
+
+모듈식 트랜스포머는 모델 폴더에 "모듈식" 파일의 개념을 도입합니다. 이 모듈식 파일은 일반적으로 모델링/프로세싱 파일에서 허용되지 않는 코드를 허용하며, 이는 인접한 모델로부터의 임포트와 클래스 간의 상속을 허용합니다.
+
+이 모듈식 파일은 각각의 별도의 모듈에서 정의되었을 모델, 프로세서 및 구성 클래스를 정의합니다.
+
+마지막으로, 이 기능은 모듈식 파일을 "풀어내어" 단일 모델, 단일 파일 디렉토리 구조로 변환하는 새로운 `linter`를 도입합니다. 이 파일들은 스크립트가 실행될 때마다 자동으로 생성되며, 기여해야 할 내용을 모듈식 파일, 그리고 기여된 모델과 다른 모델 간의 차이점으로만 줄여줍니다.
+
+모델 사용자는 단일 파일 인터페이스를 임포트하고 사용하게 되므로, 여기에는 변화가 없을 것입니다. 이를 통해 간단한 기여를 가능하게 하면서도 우리의 철학을 유지하는 양쪽의 장점을 결합하고자 합니다.
+
+따라서 이는 `# Copied from` 마커의 대체품이며, 이전에 기여된 모델은 앞으로 몇 달 내에 새로운 모듈식 트랜스포머 형식으로 전환될 예정입니다.
+
+### 자세한 내용 [[details]]
+
+“linter”는 상속 구조를 풀어서 모듈화된 파일로부터 모든 단일 파일을 생성하며, Python 사용자들에게는 그 과정이 보이지 않도록 동작합니다. 현재 linter는 **단일** 수준의 상속만을 평탄화합니다.
+
+예를 들어:
+- 구성 클래스가 다른 클래스를 상속하고 인자를 추가/삭제하는 경우, 생성된 파일은 직접 참조(추가의 경우)하거나 완전히 제거합니다(삭제의 경우).
+- 클래스가 다른 클래스를 상속하는 경우, 예를 들어 class GemmaModel(LlamaModel): 의 경우, 종속성이 자동으로 추론됩니다. 모든 서브모듈은 슈퍼클래스로부터 자동으로 추론됩니다.
+
+토크나이저, 이미지 프로세서, 모델, 구성 등을 이 `modular` 파일에 모두 작성할 수 있으며, 해당 파일들이 자동으로 생성됩니다.
+
+### 시행 [[enforcement]]
+
+[TODO] 우리는 새로운 테스트를 도입하여 생성된 콘텐츠가 `modular_xxxx.py`에 있는 내용과 일치하는지 확인합니다.
+
+### 예시 [[examples]]
+
+여기 BERT와 RoBERTa의 간단한 예가 있습니다. 두 모델은 밀접하게 관련되어 있으며, 모델 구현의 차이는 임베딩 레이어의 변경에서만 있습니다.
+
+모델을 완전히 재정의하는 대신, `modular_roberta.py` 파일은 모델링 및 구성 클래스를 위해 다음과 같이 생겼습니다. (예시를 위해, 토크나이저는 매우 다르므로 일단 무시합니다.)
+
+```python
+from torch import nn
+from ..bert.configuration_bert import BertConfig
+from ..bert.modeling_bert import (
+ BertModel,
+ BertEmbeddings,
+ BertForMaskedLM
+)
+
+# RoBERTa 구성은 BERT의 구성과 동일합니다
+class RobertaConfig(BertConfig):
+ model_type = 'roberta'
+
+# 여기서 패딩 ID 차이를 강조하기 위해 임베딩을 재정의하고, 위치 임베딩을 재정의합니다
+class RobertaEmbeddings(BertEmbeddings):
+ def __init__(self, config):
+ super().__init__(config())
+
+ self.padding_idx = config.pad_token_id
+ self.position_embeddings = nn.Embedding(
+ config.max_position_embeddings, config.hidden_size, padding_idx=self.padding_idx
+ )
+
+# RoBERTa 모델은 임베딩 레이어를 제외하면 BERT 모델과 동일합니다.
+# 위에서 임베딩을 재정의했으므로, 여기서는 추가 작업이 필요 없습니다
+class RobertaModel(BertModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.embeddings = RobertaEmbeddings(config)
+
+# 헤드는 이제 내부에서 올바른 `RobertaModel`을 재정의하기만 하면 됩니다
+class RobertaForMaskedLM(BertForMaskedLM):
+ def __init__(self, config):
+ super().__init__(config)
+ self.model = RobertaModel(config)
+```
+
+정의한 종속성을 사용하지 않으면 다음과 같은 오류가 발생합니다:
+
+```bash
+ValueError: You defined `RobertaEmbeddings` in the modular_roberta.py, it should be used
+ when you define `BertModel`, as it is one of it's direct dependencies. Make sure
+ you use it in the `__init__` function.
+```
+
+또한, 다음에서 예시 목록을 찾을 수 있습니다:
+
+## 무엇이 아닌가요 [[what-it-is-not]]
+
+(아직은?) 모델링 코드를 대체하는 것은 아닙니다. 그리고 여러분의 모델이 지금까지 존재했던 다른 어떤 것에도 기반하지 않는다면, 기존과 같이 `modeling` 파일을 추가할 수 있습니다.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/multilingual.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/multilingual.md
new file mode 100644
index 0000000000000000000000000000000000000000..c0eee024358f3e1a42ed08834183e810a271d8f8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/multilingual.md
@@ -0,0 +1,192 @@
+
+
+# 다국어 모델 추론하기[[multilingual-models-for-inference]]
+
+[[open-in-colab]]
+
+🤗 Transformers에는 여러 종류의 다국어(multilingual) 모델이 있으며, 단일 언어(monolingual) 모델과 추론 시 사용법이 다릅니다.
+그렇다고 해서 *모든* 다국어 모델의 사용법이 다른 것은 아닙니다.
+
+[google-bert/bert-base-multilingual-uncased](https://huggingface.co/google-bert/bert-base-multilingual-uncased)와 같은 몇몇 모델은 단일 언어 모델처럼 사용할 수 있습니다.
+이번 가이드에서 다국어 모델의 추론 시 사용 방법을 알아볼 것입니다.
+
+## XLM[[xlm]]
+
+XLM에는 10가지 체크포인트(checkpoint)가 있는데, 이 중 하나만 단일 언어입니다.
+나머지 체크포인트 9개는 언어 임베딩을 사용하는 체크포인트와 그렇지 않은 체크포인트의 두 가지 범주로 나눌 수 있습니다.
+
+### 언어 임베딩을 사용하는 XLM[[xlm-with-language-embeddings]]
+
+다음 XLM 모델은 추론 시에 언어 임베딩을 사용합니다:
+
+- `FacebookAI/xlm-mlm-ende-1024` (마스킹된 언어 모델링, 영어-독일어)
+- `FacebookAI/xlm-mlm-enfr-1024` (마스킹된 언어 모델링, 영어-프랑스어)
+- `FacebookAI/xlm-mlm-enro-1024` (마스킹된 언어 모델링, 영어-루마니아어)
+- `FacebookAI/xlm-mlm-xnli15-1024` (마스킹된 언어 모델링, XNLI 데이터 세트에서 제공하는 15개 국어)
+- `FacebookAI/xlm-mlm-tlm-xnli15-1024` (마스킹된 언어 모델링 + 번역, XNLI 데이터 세트에서 제공하는 15개 국어)
+- `FacebookAI/xlm-clm-enfr-1024` (Causal language modeling, 영어-프랑스어)
+- `FacebookAI/xlm-clm-ende-1024` (Causal language modeling, 영어-독일어)
+
+언어 임베딩은 모델에 전달된 `input_ids`와 동일한 shape의 텐서로 표현됩니다.
+이러한 텐서의 값은 사용된 언어에 따라 다르며 토크나이저의 `lang2id` 및 `id2lang` 속성에 의해 식별됩니다.
+
+다음 예제에서는 `FacebookAI/xlm-clm-enfr-1024` 체크포인트(코잘 언어 모델링(causal language modeling), 영어-프랑스어)를 가져옵니다:
+
+```py
+>>> import torch
+>>> from transformers import XLMTokenizer, XLMWithLMHeadModel
+
+>>> tokenizer = XLMTokenizer.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
+>>> model = XLMWithLMHeadModel.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
+```
+
+토크나이저의 `lang2id` 속성은 모델의 언어와 해당 ID를 표시합니다:
+
+```py
+>>> print(tokenizer.lang2id)
+{'en': 0, 'fr': 1}
+```
+
+다음으로, 예제 입력을 만듭니다:
+
+```py
+>>> input_ids = torch.tensor([tokenizer.encode("Wikipedia was used to")]) # 배치 크기는 1입니다
+```
+
+언어 ID를 `"en"`으로 설정해 언어 임베딩을 정의합니다.
+언어 임베딩은 영어의 언어 ID인 `0`으로 채워진 텐서입니다.
+이 텐서는 `input_ids`와 같은 크기여야 합니다.
+
+```py
+>>> language_id = tokenizer.lang2id["en"] # 0
+>>> langs = torch.tensor([language_id] * input_ids.shape[1]) # torch.tensor([0, 0, 0, ..., 0])
+
+>>> # (batch_size, sequence_length) shape의 텐서가 되도록 만듭니다.
+>>> langs = langs.view(1, -1) # 이제 [1, sequence_length] shape이 되었습니다(배치 크기는 1입니다)
+```
+
+이제 `input_ids`와 언어 임베딩을 모델로 전달합니다:
+
+```py
+>>> outputs = model(input_ids, langs=langs)
+```
+
+[run_generation.py](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-generation/run_generation.py) 스크립트로 `xlm-clm` 체크포인트를 사용해 텍스트와 언어 임베딩을 생성할 수 있습니다.
+
+### 언어 임베딩을 사용하지 않는 XLM[[xlm-without-language-embeddings]]
+
+다음 XLM 모델은 추론 시에 언어 임베딩이 필요하지 않습니다:
+
+- `FacebookAI/xlm-mlm-17-1280` (마스킹된 언어 모델링, 17개 국어)
+- `FacebookAI/xlm-mlm-100-1280` (마스킹된 언어 모델링, 100개 국어)
+
+이전의 XLM 체크포인트와 달리 이 모델은 일반 문장 표현에 사용됩니다.
+
+## BERT[[bert]]
+
+다음 BERT 모델은 다국어 태스크에 사용할 수 있습니다:
+
+- `google-bert/bert-base-multilingual-uncased` (마스킹된 언어 모델링 + 다음 문장 예측, 102개 국어)
+- `google-bert/bert-base-multilingual-cased` (마스킹된 언어 모델링 + 다음 문장 예측, 104개 국어)
+
+이러한 모델은 추론 시에 언어 임베딩이 필요하지 않습니다.
+문맥에서 언어를 식별하고, 식별된 언어로 추론합니다.
+
+## XLM-RoBERTa[[xlmroberta]]
+
+다음 XLM-RoBERTa 또한 다국어 다국어 태스크에 사용할 수 있습니다:
+
+- `FacebookAI/xlm-roberta-base` (마스킹된 언어 모델링, 100개 국어)
+- `FacebookAI/xlm-roberta-large` (마스킹된 언어 모델링, 100개 국어)
+
+XLM-RoBERTa는 100개 국어에 대해 새로 생성되고 정제된 2.5TB 규모의 CommonCrawl 데이터로 학습되었습니다.
+이전에 공개된 mBERT나 XLM과 같은 다국어 모델에 비해 분류, 시퀀스 라벨링, 질의 응답과 같은 다운스트림(downstream) 작업에서 이점이 있습니다.
+
+## M2M100[[m2m100]]
+
+다음 M2M100 모델 또한 다국어 다국어 태스크에 사용할 수 있습니다:
+
+- `facebook/m2m100_418M` (번역)
+- `facebook/m2m100_1.2B` (번역)
+
+이 예제에서는 `facebook/m2m100_418M` 체크포인트를 가져와서 중국어를 영어로 번역합니다.
+토크나이저에서 번역 대상 언어(source language)를 설정할 수 있습니다:
+
+```py
+>>> from transformers import M2M100ForConditionalGeneration, M2M100Tokenizer
+
+>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
+>>> chinese_text = "不要插手巫師的事務, 因為他們是微妙的, 很快就會發怒."
+
+>>> tokenizer = M2M100Tokenizer.from_pretrained("facebook/m2m100_418M", src_lang="zh")
+>>> model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M")
+```
+
+문장을 토큰화합니다:
+
+```py
+>>> encoded_zh = tokenizer(chinese_text, return_tensors="pt")
+```
+
+M2M100은 번역을 진행하기 위해 첫 번째로 생성되는 토큰은 번역할 언어(target language) ID로 강제 지정합니다.
+영어로 번역하기 위해 `generate` 메소드에서 `forced_bos_token_id`를 `en`으로 설정합니다:
+
+```py
+>>> generated_tokens = model.generate(**encoded_zh, forced_bos_token_id=tokenizer.get_lang_id("en"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+'Do not interfere with the matters of the witches, because they are delicate and will soon be angry.'
+```
+
+## MBart[[mbart]]
+
+다음 MBart 모델 또한 다국어 태스크에 사용할 수 있습니다:
+
+- `facebook/mbart-large-50-one-to-many-mmt` (일대다 다국어 번역, 50개 국어)
+- `facebook/mbart-large-50-many-to-many-mmt` (다대다 다국어 번역, 50개 국어)
+- `facebook/mbart-large-50-many-to-one-mmt` (다대일 다국어 번역, 50개 국어)
+- `facebook/mbart-large-50` (다국어 번역, 50개 국어)
+- `facebook/mbart-large-cc25`
+
+이 예제에서는 핀란드어를 영어로 번역하기 위해 `facebook/mbart-large-50-many-to-many-mmt` 체크포인트를 가져옵니다.
+토크나이저에서 번역 대상 언어(source language)를 설정할 수 있습니다:
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
+>>> fi_text = "Älä sekaannu velhojen asioihin, sillä ne ovat hienovaraisia ja nopeasti vihaisia."
+
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/mbart-large-50-many-to-many-mmt", src_lang="fi_FI")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/mbart-large-50-many-to-many-mmt")
+```
+
+문장을 토큰화합니다:
+
+```py
+>>> encoded_en = tokenizer(en_text, return_tensors="pt")
+```
+
+MBart는 번역을 진행하기 위해 첫 번째로 생성되는 토큰은 번역할 언어(target language) ID로 강제 지정합니다.
+영어로 번역하기 위해 `generate` 메소드에서 `forced_bos_token_id`를 `en`으로 설정합니다:
+
+```py
+>>> generated_tokens = model.generate(**encoded_en, forced_bos_token_id=tokenizer.lang_code_to_id("en_XX"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+"Don't interfere with the wizard's affairs, because they are subtle, will soon get angry."
+```
+
+`facebook/mbart-large-50-many-to-one-mmt` 체크포인트를 사용하고 있다면, 첫 번째로 생성되는 토큰을 번역할 언어(target language) ID로 강제 지정할 필요는 없습니다.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/pad_truncation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/pad_truncation.md
new file mode 100644
index 0000000000000000000000000000000000000000..9ee4dc839b8416f2114b0a12e7e86ada591926a6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/pad_truncation.md
@@ -0,0 +1,68 @@
+
+
+# 패딩과 잘라내기[[padding-and-truncation]]
+
+배치 입력은 길이가 다른 경우가 많아서 고정 크기 텐서로 변환할 수 없습니다. 패딩과 잘라내기는 다양한 길이의 배치에서 직사각형 텐서를 생성할 수 있도록 이 문제를 해결하는 전략입니다. 패딩은 특수한 **패딩 토큰**을 추가하여 짧은 시퀀스가 배치에서 가장 긴 시퀀스 또는 모델에서 허용하는 최대 길이와 동일한 길이를 갖도록 합니다. 잘라내기는 긴 시퀀스를 잘라내어 패딩과 다른 방식으로 시퀀스의 길이를 동일하게 합니다.
+
+대부분의 경우 배치에 가장 긴 시퀀스의 길이로 패딩하고 모델이 허용할 수 있는 최대 길이로 잘라내는 것이 잘 작동합니다. 그러나 필요하다면 API가 지원하는 더 많은 전략을 사용할 수 있습니다. 필요한 인수는 `padding`, `truncation`, `max_length` 세 가지입니다.
+
+`padding` 인수는 패딩을 제어합니다. 불리언 또는 문자열일 수 있습니다:
+
+ - `True` 또는 `'longest'`: 배치에서 가장 긴 시퀀스로 패딩합니다(단일 시퀀스만 제공하는 경우 패딩이 적용되지 않습니다).
+ - `'max_length'`: `max_length` 인수가 지정한 길이로 패딩하거나, `max_length`가 제공되지 않은 경우(`max_length=None`) 모델에서 허용되는 최대 길이로 패딩합니다. 단일 시퀀스만 제공하는 경우에도 패딩이 적용됩니다.
+ - `False` 또는 `'do_not_pad'`: 패딩이 적용되지 않습니다. 이것이 기본 동작입니다.
+
+`truncation` 인수는 잘라낼 방법을 정합니다. 불리언 또는 문자열일 수 있습니다:
+
+ - `True` 또는 `longest_first`: `max_length` 인수가 지정한 최대 길이로 잘라내거나,
+ `max_length`가 제공되지 않은 경우(`max_length=None`) 모델에서 허용되는 최대 길이로 잘라냅니다.
+ 시퀀스 쌍에서 가장 긴 시퀀스의 토큰을 적절한 길이에 도달할 때까지 하나씩 제거합니다.
+ - `'only_second'`: `max_length` 인수가 지정한 최대 길이로 잘라내거나,
+ `max_length`가 제공되지 않은 경우(`max_length=None`) 모델에서 허용되는 최대 길이로 잘라냅니다.
+ 시퀀스 쌍(또는 시퀀스 쌍의 배치)가 제공된 경우 쌍의 두 번째 문장만 잘라냅니다.
+ - `'only_first'`: `max_length` 인수가 지정한 최대 길이로 잘라내거나,
+ `max_length`가 제공되지 않은 경우(`max_length=None`) 모델에서 허용되는 최대 길이로 잘라냅니다.
+ 시퀀스 쌍(또는 시퀀스 쌍의 배치)가 제공된 경우 쌍의 첫 번째 문장만 잘라냅니다.
+ - `False` 또는 `'do_not_truncate'`: 잘라내기를 적용하지 않습니다. 이것이 기본 동작입니다.
+
+`max_length` 인수는 패딩 및 잘라내기를 적용할 길이를 제어합니다. 이 인수는 정수 또는 `None`일 수 있으며, `None`일 경우 모델이 허용할 수 있는 최대 길이로 기본값이 설정됩니다. 모델에 특정한 최대 입력 길이가 없는 경우 `max_length`에 대한 잘라내기 또는 패딩이 비활성화됩니다.
+
+다음 표에는 패딩 및 잘라내기를 설정하는 권장 방법이 요약되어 있습니다.
+입력으로 시퀀스 쌍을 사용하는 경우, 다음 예제에서 `truncation=True`를 `['only_first', 'only_second', 'longest_first']`에서 선택한 `STRATEGY`, 즉 `truncation='only_second'` 또는 `truncation='longest_first'`로 바꾸면 앞서 설명한 대로 쌍의 두 시퀀스가 잘리는 방식을 제어할 수 있습니다.
+
+| 잘라내기 | 패딩 | 사용 방법 |
+|--------------------------------------|-----------------------------------|------------------------------------------------------------------------------------------|
+| 잘라내기 없음 | 패딩 없음 | `tokenizer(batch_sentences)` |
+| | 배치 내 최대 길이로 패딩 | `tokenizer(batch_sentences, padding=True)` 또는 |
+| | | `tokenizer(batch_sentences, padding='longest')` |
+| | 모델의 최대 입력 길이로 패딩 | `tokenizer(batch_sentences, padding='max_length')` |
+| | 특정 길이로 패딩 | `tokenizer(batch_sentences, padding='max_length', max_length=42)` |
+| | 다양한 길이로 패딩 | `tokenizer(batch_sentences, padding=True, pad_to_multiple_of=8)` |
+| 모델의 최대 입력 길이로 잘라내기 | 패딩 없음 | `tokenizer(batch_sentences, truncation=True)` 또는 |
+| | | `tokenizer(batch_sentences, truncation=STRATEGY)` |
+| | 배치 내 최대 길이로 패딩 | `tokenizer(batch_sentences, padding=True, truncation=True)` 또는 |
+| | | `tokenizer(batch_sentences, padding=True, truncation=STRATEGY)` |
+| | 모델의 최대 입력 길이로 패딩 | `tokenizer(batch_sentences, padding='max_length', truncation=True)` 또는 |
+| | | `tokenizer(batch_sentences, padding='max_length', truncation=STRATEGY)` |
+| | 특정 길이로 패딩 | 사용 불가 |
+| 특정 길이로 잘라내기 | 패딩 없음 | `tokenizer(batch_sentences, truncation=True, max_length=42)` 또는 |
+| | | `tokenizer(batch_sentences, truncation=STRATEGY, max_length=42)` |
+| | 배치 내 최대 길이로 패딩 | `tokenizer(batch_sentences, padding=True, truncation=True, max_length=42)` 또는 |
+| | | `tokenizer(batch_sentences, padding=True, truncation=STRATEGY, max_length=42)` |
+| | 모델의 최대 입력 길이로 패딩 | 사용 불가 |
+| | 특정 길이로 패딩 | `tokenizer(batch_sentences, padding='max_length', truncation=True, max_length=42)` 또는 |
+| | | `tokenizer(batch_sentences, padding='max_length', truncation=STRATEGY, max_length=42)` |
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/peft.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/peft.md
new file mode 100644
index 0000000000000000000000000000000000000000..d4ef0ba539e2de598a6d7504908f632c34e7c560
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/peft.md
@@ -0,0 +1,209 @@
+
+
+# 🤗 PEFT로 어댑터 가져오기 [[load-adapters-with-peft]]
+
+[[open-in-colab]]
+
+[Parameter-Efficient Fine Tuning (PEFT)](https://huggingface.co/blog/peft) 방법은 사전훈련된 모델의 매개변수를 미세 조정 중 고정시키고, 그 위에 훈련할 수 있는 매우 적은 수의 매개변수(어댑터)를 추가합니다. 어댑터는 작업별 정보를 학습하도록 훈련됩니다. 이 접근 방식은 완전히 미세 조정된 모델에 필적하는 결과를 생성하면서, 메모리 효율적이고 비교적 적은 컴퓨팅 리소스를 사용합니다.
+
+또한 PEFT로 훈련된 어댑터는 일반적으로 전체 모델보다 훨씬 작기 때문에 공유, 저장 및 가져오기가 편리합니다.
+
+
+
+
Hub에 저장된 OPTForCausalLM 모델의 어댑터 가중치는 최대 700MB에 달하는 모델 가중치의 전체 크기에 비해 약 6MB에 불과합니다.
+
+
+`AutoModelFor` 클래스나 기본 모델 클래스(예: `OPTForCausalLM` 또는 `LlamaForCausalLM`) 중 하나를 사용하여 PEFT 어댑터를 가져올 수 있습니다.
+
+
+
+`load_adapter` 메소드를 호출하여 PEFT 어댑터를 가져올 수도 있습니다.
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_id = "facebook/opt-350m"
+peft_model_id = "ybelkada/opt-350m-lora"
+
+model = AutoModelForCausalLM.from_pretrained(model_id)
+model.load_adapter(peft_model_id)
+```
+
+## 8비트 또는 4비트로 가져오기 [[load-in-8bit-or-4bit]]
+
+`bitsandbytes` 통합은 8비트와 4비트 정밀도 데이터 유형을 지원하므로 큰 모델을 가져올 때 유용하면서 메모리도 절약합니다. 모델을 하드웨어에 효과적으로 분배하려면 [`~PreTrainedModel.from_pretrained`]에 `load_in_8bit` 또는 `load_in_4bit` 매개변수를 추가하고 `device_map="auto"`를 설정하세요:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+peft_model_id = "ybelkada/opt-350m-lora"
+model = AutoModelForCausalLM.from_pretrained(peft_model_id, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+```
+
+## 새 어댑터 추가 [[add-a-new-adapter]]
+
+새 어댑터가 현재 어댑터와 동일한 유형인 경우에 한해 기존 어댑터가 있는 모델에 새 어댑터를 추가하려면 [`~peft.PeftModel.add_adapter`]를 사용할 수 있습니다. 예를 들어 모델에 기존 LoRA 어댑터가 연결되어 있는 경우:
+
+```py
+from transformers import AutoModelForCausalLM, OPTForCausalLM, AutoTokenizer
+from peft import PeftConfig
+
+model_id = "facebook/opt-350m"
+model = AutoModelForCausalLM.from_pretrained(model_id)
+
+lora_config = LoraConfig(
+ target_modules=["q_proj", "k_proj"],
+ init_lora_weights=False
+)
+
+model.add_adapter(lora_config, adapter_name="adapter_1")
+```
+
+새 어댑터를 추가하려면:
+
+```py
+# attach new adapter with same config
+model.add_adapter(lora_config, adapter_name="adapter_2")
+```
+
+이제 [`~peft.PeftModel.set_adapter`]를 사용하여 어댑터를 사용할 어댑터로 설정할 수 있습니다:
+
+```py
+# use adapter_1
+model.set_adapter("adapter_1")
+output = model.generate(**inputs)
+print(tokenizer.decode(output_disabled[0], skip_special_tokens=True))
+
+# use adapter_2
+model.set_adapter("adapter_2")
+output_enabled = model.generate(**inputs)
+print(tokenizer.decode(output_enabled[0], skip_special_tokens=True))
+```
+
+## 어댑터 활성화 및 비활성화 [[enable-and-disable-adapters]]
+
+모델에 어댑터를 추가한 후 어댑터 모듈을 활성화 또는 비활성화할 수 있습니다. 어댑터 모듈을 활성화하려면:
+
+```py
+from transformers import AutoModelForCausalLM, OPTForCausalLM, AutoTokenizer
+from peft import PeftConfig
+
+model_id = "facebook/opt-350m"
+adapter_model_id = "ybelkada/opt-350m-lora"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+text = "Hello"
+inputs = tokenizer(text, return_tensors="pt")
+
+model = AutoModelForCausalLM.from_pretrained(model_id)
+peft_config = PeftConfig.from_pretrained(adapter_model_id)
+
+# to initiate with random weights
+peft_config.init_lora_weights = False
+
+model.add_adapter(peft_config)
+model.enable_adapters()
+output = model.generate(**inputs)
+```
+
+어댑터 모듈을 비활성화하려면:
+
+```py
+model.disable_adapters()
+output = model.generate(**inputs)
+```
+
+## PEFT 어댑터 훈련 [[train-a-peft-adapter]]
+
+PEFT 어댑터는 [`Trainer`] 클래스에서 지원되므로 특정 사용 사례에 맞게 어댑터를 훈련할 수 있습니다. 몇 줄의 코드를 추가하기만 하면 됩니다. 예를 들어 LoRA 어댑터를 훈련하려면:
+
+
+
+[`Trainer`]를 사용하여 모델을 미세 조정하는 것이 익숙하지 않다면 [사전훈련된 모델을 미세 조정하기](training) 튜토리얼을 확인하세요.
+
+
+
+1. 작업 유형 및 하이퍼파라미터를 지정하여 어댑터 구성을 정의합니다. 하이퍼파라미터에 대한 자세한 내용은 [`~peft.LoraConfig`]를 참조하세요.
+
+```py
+from peft import LoraConfig
+
+peft_config = LoraConfig(
+ lora_alpha=16,
+ lora_dropout=0.1,
+ r=64,
+ bias="none",
+ task_type="CAUSAL_LM",
+)
+```
+
+2. 모델에 어댑터를 추가합니다.
+
+```py
+model.add_adapter(peft_config)
+```
+
+3. 이제 모델을 [`Trainer`]에 전달할 수 있습니다!
+
+```py
+trainer = Trainer(model=model, ...)
+trainer.train()
+```
+
+훈련한 어댑터를 저장하고 다시 가져오려면:
+
+```py
+model.save_pretrained(save_dir)
+model = AutoModelForCausalLM.from_pretrained(save_dir)
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_hardware.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_hardware.md
new file mode 100644
index 0000000000000000000000000000000000000000..01282a0c711147318121f71e07e1a638549906cc
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_hardware.md
@@ -0,0 +1,156 @@
+
+
+
+# 훈련용 사용자 맞춤형 하드웨어 [[custom-hardware-for-training]]
+
+모델 훈련과 추론에 사용하는 하드웨어는 성능에 큰 영향을 미칠 수 있습니다. GPU에 대해 자세히 알아보려면, Tim Dettmer의 훌륭한 블로그 포스트를 확인해보세요. [블로그 포스트 링크](https://timdettmers.com/2020/09/07/which-gpu-for-deep-learning/) (영어로 작성됨).
+
+GPU 설정에 대한 실용적인 조언을 살펴보겠습니다.
+
+## GPU [[gpu]]
+더 큰 모델을 훈련시킬 때는 기본적으로 세 가지 옵션이 있습니다:
+
+- 더 큰 GPU
+- 더 많은 GPU
+- 더 많은 CPU 및 NVMe ([DeepSpeed-Infinity](../en/main_classes/deepspeed#nvme-support)를 통한 오프로드(offload))
+
+우선, 하나의 GPU만 사용하는 경우부터 시작해봅시다.
+
+### 전원 공급과 냉각 [[power-and-cooling]]
+
+비싼 고성능 GPU를 구매한 경우, 올바른 전원 공급과 충분한 냉각을 제공해야 합니다.
+
+**전원 공급**:
+
+일부 고성능 소비자용 GPU는 2개 혹은 가끔가다 3개의 PCI-E 8핀 전원 소켓이 있습니다. 카드에 있는 소켓 수만큼 독립적인 12V PCI-E 8핀 케이블이 연결되어 있는지 확인하세요. 같은 케이블의 한쪽 끝에 있는 2개의 스플릿(또는 피그테일(pigtail) 케이블)을 사용하지 마세요. 즉, GPU에 2개의 소켓이 있다면, PSU(전원 공급 장치)에서 카드로 연결되는 2개의 PCI-E 8핀 케이블이 필요하며, 끝에 2개의 PCI-E 8핀 커넥터가 있는 케이블이 필요하지 않습니다! 그렇지 않으면 카드의 전체 성능을 제대로 발휘하지 못할 수 있습니다.
+
+각각의 PCI-E 8핀 전원 케이블은 PSU 쪽의 12V 레일에 연결되어야 하며 최대 150W의 전력을 공급할 수 있습니다.
+
+일부 다른 GPU는 PCI-E 12핀 커넥터를 사용하며, 이러한 커넥터는 최대 500W-600W의 전력을 공급할 수 있습니다.
+
+저가형 GPU는 6핀 커넥터를 사용하며, 최대 75W의 전력을 공급합니다.
+
+또한 GPU가 안정적인 전압을 받을 수 있도록 고급 PSU를 선택해야 합니다. 일부 저품질의 PSU는 GPU가 최고 성능으로 동작하기 위해 필요한 전압을 안정적으로 공급하지 못할 수 있습니다.
+
+물론, PSU는 GPU에 전원을 공급하기에 충분한 여분의 전력 용량을 가져야 합니다.
+
+**냉각**:
+
+GPU가 과열되면 성능이 저하되고 최대 성능을 발휘하지 못할 수 있으며, 너무 뜨거워지면 중지될 수 있습니다.
+
+GPU가 과열될 때 정확한 적정 온도를 알기 어려우나, 아마도 +80℃ 미만이면 좋지만 더 낮을수록 좋습니다. 70℃-75℃ 정도가 훌륭한 온도 범위입니다. 성능 저하가 발생하기 시작하는 온도는 대략 84℃-90℃ 정도일 것입니다. 하지만 성능 저하 이외에도 지속적으로 매우 높은 온도는 GPU 수명을 단축시킬 수 있습니다.
+
+이어서, 여러 개의 GPU를 사용할 때 가장 중요한 측면 중 하나인 GPU 간 연결 방식을 살펴보겠습니다.
+
+### 다중 GPU 연결 방식 [[multigpu-connectivity]]
+
+다중 GPU를 사용하는 경우 GPU 간의 연결 방식은 전체 훈련 시간에 큰 영향을 미칠 수 있습니다. 만약 GPU가 동일한 물리적 노드에 있을 경우, 다음과 같이 확인할 수 있습니다:
+
+```bash
+nvidia-smi topo -m
+```
+
+만약 NVLink로 연결된 듀얼 GPU 환경이라면, 다음과 같은 결과를 확인할 수 있습니다:
+
+```
+ GPU0 GPU1 CPU Affinity NUMA Affinity
+GPU0 X NV2 0-23 N/A
+GPU1 NV2 X 0-23 N/A
+```
+
+NVLink를 지원하지 않는 다른 환경의 경우에는 다음과 같은 결과를 확인할 수 있습니다:
+```
+ GPU0 GPU1 CPU Affinity NUMA Affinity
+GPU0 X PHB 0-11 N/A
+GPU1 PHB X 0-11 N/A
+```
+
+이 결과에는 다음과 같은 범례가 포함되어 있습니다:
+
+```
+ X = Self
+ SYS = Connection traversing PCIe as well as the SMP interconnect between NUMA nodes (e.g., QPI/UPI)
+ NODE = Connection traversing PCIe as well as the interconnect between PCIe Host Bridges within a NUMA node
+ PHB = Connection traversing PCIe as well as a PCIe Host Bridge (typically the CPU)
+ PXB = Connection traversing multiple PCIe bridges (without traversing the PCIe Host Bridge)
+ PIX = Connection traversing at most a single PCIe bridge
+ NV# = Connection traversing a bonded set of # NVLinks
+```
+
+따라서 첫 번째 결과의 `NV2`는 GPU가 2개의 NVLink로 연결되어 있다는 것을 나타내고, 두 번째 결과의 `PHB`는 일반적인 소비자용 PCIe+브릿지 설정을 가지고 있다는 것을 나타냅니다.
+
+설정에서 어떤 유형의 연결 방식을 가지고 있는지 확인하세요. 일부 연결 방식은 GPU 간 통신을 더 빠르게 만들 수 있으며(NVLink와 같이), 어떤 연결 방식은 더 느리게 만들 수 있습니다(PHB와 같이).
+
+사용하는 확장성 솔루션의 종류에 따라 연결 속도가 주요한 영향을 미칠 수도 있고 미미한 영향을 미칠 수도 있습니다. DDP와 같이 GPU가 거의 동기화하지 않아도 되는 경우, 연결 속도가 느려도 큰 영향을 받지 않습니다. 반면 ZeRO-DP와 같이 GPU간 통신이 많이 필요한 경우, 더 빠른 훈련을 위해서는 더 빠른 연결 속도가 중요합니다.
+
+#### NVLink [[nvlink]]
+
+[NVLink](https://en.wikipedia.org/wiki/NVLink)는 Nvidia에서 개발한 유선 기반의 직렬 다중 레인 근거리 통신 링크입니다.
+
+새로운 세대의 NVLink는 더 빠른 대역폭을 제공합니다. [Nvidia Ampere GA102 GPU Architecture](https://www.nvidia.com/content/dam/en-zz/Solutions/geforce/ampere/pdf/NVIDIA-ampere-GA102-GPU-Architecture-Whitepaper-V1.pdf)에서 아래와 같은 정보를 확인하실 수 있습니다:
+
+> 3세대 NVLink®
+> GA102 GPU는 4개의 x4 링크를 포함하는 NVIDIA의 3세대 NVLink 인터페이스를 활용하며,
+> 각 링크는 두 개의 GPU 간에 각 방향으로 초당 14.0625GB의 대역폭을 제공합니다.
+> 4개의 링크는 각 방향에 초당 56.25GB의 대역폭을 제공하며, 두 개의 GPU 간에는 초당 112.5GB의 총 대역폭을 제공합니다.
+> 두 개의 RTX 3090 GPU를 NVLink를 사용해 SLI로 연결할 수 있습니다.
+> (3-Way 및 4-Way SLI 구성은 지원되지 않음에 유의하세요.)
+
+
+따라서 `nvidia-smi topo -m`의 결과에서 `NVX`의 값이 높을수록 더 좋습니다. 세대는 GPU 아키텍처에 따라 다를 수 있습니다.
+
+그렇다면, openai-community/gpt2를 작은 wikitext 샘플로 학습시키는 예제를 통해, NVLink가 훈련에 어떤 영향을 미치는지 살펴보겠습니다.
+
+결과는 다음과 같습니다:
+
+
+| NVlink | Time |
+| ----- | ---: |
+| Y | 101s |
+| N | 131s |
+
+
+NVLink 사용 시 훈련이 약 23% 더 빠르게 완료됨을 확인할 수 있습니다. 두 번째 벤치마크에서는 `NCCL_P2P_DISABLE=1`을 사용하여 NVLink를 사용하지 않도록 설정했습니다.
+
+전체 벤치마크 코드와 결과는 다음과 같습니다:
+
+```bash
+# DDP w/ NVLink
+
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 torchrun \
+--nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py --model_name_or_path openai-community/gpt2 \
+--dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 --do_train \
+--output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 101.9003, 'train_samples_per_second': 1.963, 'epoch': 0.69}
+
+# DDP w/o NVLink
+
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 NCCL_P2P_DISABLE=1 torchrun \
+--nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py --model_name_or_path openai-community/gpt2 \
+--dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 --do_train
+--output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 131.4367, 'train_samples_per_second': 1.522, 'epoch': 0.69}
+```
+
+하드웨어: 각각 2개의 TITAN RTX 24GB + 2개의 NVLink (`NV2` in `nvidia-smi topo -m`)
+소프트웨어: `pytorch-1.8-to-be` + `cuda-11.0` / `transformers==4.3.0.dev0`
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_infer_cpu.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_infer_cpu.md
new file mode 100644
index 0000000000000000000000000000000000000000..123e56b4f32c2fdf6d90f7e127c74a0a3803d5ea
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_infer_cpu.md
@@ -0,0 +1,73 @@
+
+
+# CPU에서 효율적인 추론하기 [[efficient-inference-on-cpu]]
+
+이 가이드는 CPU에서 대규모 모델을 효율적으로 추론하는 방법에 중점을 두고 있습니다.
+
+## 더 빠른 추론을 위한 `BetterTransformer` [[bettertransformer-for-faster-inference]]
+
+우리는 최근 CPU에서 텍스트, 이미지 및 오디오 모델의 빠른 추론을 위해 `BetterTransformer`를 통합했습니다. 이 통합에 대한 더 자세한 내용은 [이 문서](https://huggingface.co/docs/optimum/bettertransformer/overview)를 참조하세요.
+
+## PyTorch JIT 모드 (TorchScript) [[pytorch-jitmode-torchscript]]
+TorchScript는 PyTorch 코드에서 직렬화와 최적화가 가능한 모델을 생성할때 쓰입니다. TorchScript로 만들어진 프로그램은 기존 Python 프로세스에서 저장한 뒤, 종속성이 없는 새로운 프로세스로 가져올 수 있습니다. PyTorch의 기본 설정인 `eager` 모드와 비교했을때, `jit` 모드는 연산자 결합과 같은 최적화 방법론을 통해 모델 추론에서 대부분 더 나은 성능을 제공합니다.
+
+TorchScript에 대한 친절한 소개는 [PyTorch TorchScript 튜토리얼](https://pytorch.org/tutorials/beginner/Intro_to_TorchScript_tutorial.html#tracing-modules)을 참조하세요.
+
+### JIT 모드와 함께하는 IPEX 그래프 최적화 [[ipex-graph-optimization-with-jitmode]]
+Intel® Extension for PyTorch(IPEX)는 Transformers 계열 모델의 jit 모드에서 추가적인 최적화를 제공합니다. jit 모드와 더불어 Intel® Extension for PyTorch(IPEX)를 활용하시길 강력히 권장드립니다. Transformers 모델에서 자주 사용되는 일부 연산자 패턴은 이미 jit 모드 연산자 결합(operator fusion)의 형태로 Intel® Extension for PyTorch(IPEX)에서 지원되고 있습니다. Multi-head-attention, Concat Linear, Linear+Add, Linear+Gelu, Add+LayerNorm 결합 패턴 등이 이용 가능하며 활용했을 때 성능이 우수합니다. 연산자 결합의 이점은 사용자에게 고스란히 전달됩니다. 분석에 따르면, 질의 응답, 텍스트 분류 및 토큰 분류와 같은 가장 인기 있는 NLP 태스크 중 약 70%가 이러한 결합 패턴을 사용하여 Float32 정밀도와 BFloat16 혼합 정밀도 모두에서 성능상의 이점을 얻을 수 있습니다.
+
+[IPEX 그래프 최적화](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/features/graph_optimization.html)에 대한 자세한 정보를 확인하세요.
+
+#### IPEX 설치: [[ipex-installation]]
+
+IPEX 배포 주기는 PyTorch를 따라서 이루어집니다. 자세한 정보는 [IPEX 설치 방법](https://intel.github.io/intel-extension-for-pytorch/)을 확인하세요.
+
+### JIT 모드 사용법 [[usage-of-jitmode]]
+평가 또는 예측을 위해 Trainer에서 JIT 모드를 사용하려면 Trainer의 명령 인수에 `jit_mode_eval`을 추가해야 합니다.
+
+
+
+PyTorch의 버전이 1.14.0 이상이라면, jit 모드는 jit.trace에서 dict 입력이 지원되므로, 모든 모델의 예측과 평가가 개선될 수 있습니다.
+
+PyTorch의 버전이 1.14.0 미만이라면, 질의 응답 모델과 같이 forward 매개변수의 순서가 jit.trace의 튜플 입력 순서와 일치하는 모델에 득이 될 수 있습니다. 텍스트 분류 모델과 같이 forward 매개변수 순서가 jit.trace의 튜플 입력 순서와 다른 경우, jit.trace가 실패하며 예외가 발생합니다. 이때 예외상황을 사용자에게 알리기 위해 Logging이 사용됩니다.
+
+
+
+[Transformers 질의 응답](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)의 사용 사례 예시를 참조하세요.
+
+
+- CPU에서 jit 모드를 사용한 추론:
+python run_qa.py \
+--model_name_or_path csarron/bert-base-uncased-squad-v1 \
+--dataset_name squad \
+--do_eval \
+--max_seq_length 384 \
+--doc_stride 128 \
+--output_dir /tmp/ \
+--no_cuda \
+--jit_mode_eval
+
+- CPU에서 IPEX와 함께 jit 모드를 사용한 추론:
+python run_qa.py \
+--model_name_or_path csarron/bert-base-uncased-squad-v1 \
+--dataset_name squad \
+--do_eval \
+--max_seq_length 384 \
+--doc_stride 128 \
+--output_dir /tmp/ \
+--no_cuda \
+--use_ipex \
+--jit_mode_eval
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_infer_gpu_one.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_infer_gpu_one.md
new file mode 100644
index 0000000000000000000000000000000000000000..d6ddca6cd039cb54e6b3d273a7336f6a4e73ac8c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_infer_gpu_one.md
@@ -0,0 +1,184 @@
+
+
+# 단일 GPU에서 효율적인 추론 [[efficient-inference-on-a-single-gpu]]
+
+이 가이드 외에도, [단일 GPU에서의 훈련 가이드](perf_train_gpu_one)와 [CPU에서의 추론 가이드](perf_infer_cpu)에서도 관련 정보를 찾을 수 있습니다.
+
+## Better Transformer: PyTorch 네이티브 Transformer 패스트패스 [[better-transformer-pytorchnative-transformer-fastpath]]
+
+PyTorch 네이티브 [`nn.MultiHeadAttention`](https://pytorch.org/blog/a-better-transformer-for-fast-transformer-encoder-inference/) 어텐션 패스트패스인 BetterTransformer는 [🤗 Optimum 라이브러리](https://huggingface.co/docs/optimum/bettertransformer/overview)의 통합을 통해 Transformers와 함께 사용할 수 있습니다.
+
+PyTorch의 어텐션 패스트패스는 커널 퓨전과 [중첩된 텐서](https://pytorch.org/docs/stable/nested.html)의 사용을 통해 추론 속도를 높일 수 있습니다. 자세한 벤치마크는 [이 블로그 글](https://medium.com/pytorch/bettertransformer-out-of-the-box-performance-for-huggingface-transformers-3fbe27d50ab2)에서 확인할 수 있습니다.
+
+[`optimum`](https://github.com/huggingface/optimum) 패키지를 설치한 후에는 추론 중 Better Transformer를 사용할 수 있도록 [`~PreTrainedModel.to_bettertransformer`]를 호출하여 관련 내부 모듈을 대체합니다:
+
+```python
+model = model.to_bettertransformer()
+```
+
+[`~PreTrainedModel.reverse_bettertransformer`] 메소드는 정규화된 transformers 모델링을 사용하기 위해 모델을 저장하기 전 원래의 모델링으로 돌아갈 수 있도록 해줍니다:
+
+```python
+model = model.reverse_bettertransformer()
+model.save_pretrained("saved_model")
+```
+
+PyTorch 2.0부터는 어텐션 패스트패스가 인코더와 디코더 모두에서 지원됩니다. 지원되는 아키텍처 목록은 [여기](https://huggingface.co/docs/optimum/bettertransformer/overview#supported-models)에서 확인할 수 있습니다.
+
+## FP4 혼합 정밀도 추론을 위한 `bitsandbytes` 통합 [[bitsandbytes-integration-for-fp4-mixedprecision-inference]]
+
+`bitsandbytes`를 설치하면 GPU에서 손쉽게 모델을 압축할 수 있습니다. FP4 양자화를 사용하면 원래의 전체 정밀도 버전과 비교하여 모델 크기를 최대 8배 줄일 수 있습니다. 아래에서 시작하는 방법을 확인하세요.
+
+
+
+이 기능은 다중 GPU 설정에서도 사용할 수 있습니다.
+
+
+
+### 요구 사항 [[requirements-for-fp4-mixedprecision-inference]]
+
+- 최신 `bitsandbytes` 라이브러리
+`pip install bitsandbytes>=0.39.0`
+
+- 최신 `accelerate`를 소스에서 설치
+`pip install git+https://github.com/huggingface/accelerate.git`
+
+- 최신 `transformers`를 소스에서 설치
+`pip install git+https://github.com/huggingface/transformers.git`
+
+### FP4 모델 실행 - 단일 GPU 설정 - 빠른 시작 [[running-fp4-models-single-gpu-setup-quickstart]]
+
+다음 코드를 실행하여 단일 GPU에서 빠르게 FP4 모델을 실행할 수 있습니다.
+
+```py
+from transformers import AutoModelForCausalLM
+
+model_name = "bigscience/bloom-2b5"
+model_4bit = AutoModelForCausalLM.from_pretrained(model_name, device_map="auto", load_in_4bit=True)
+```
+`device_map`은 선택 사항입니다. 그러나 `device_map = 'auto'`로 설정하는 것이 사용 가능한 리소스를 효율적으로 디스패치하기 때문에 추론에 있어 권장됩니다.
+
+### FP4 모델 실행 - 다중 GPU 설정 [[running-fp4-models-multi-gpu-setup]]
+
+다중 GPU에서 혼합 4비트 모델을 가져오는 방법은 단일 GPU 설정과 동일합니다(동일한 명령어 사용):
+```py
+model_name = "bigscience/bloom-2b5"
+model_4bit = AutoModelForCausalLM.from_pretrained(model_name, device_map="auto", load_in_4bit=True)
+```
+하지만 `accelerate`를 사용하여 각 GPU에 할당할 GPU RAM을 제어할 수 있습니다. 다음과 같이 `max_memory` 인수를 사용하세요:
+
+```py
+max_memory_mapping = {0: "600MB", 1: "1GB"}
+model_name = "bigscience/bloom-3b"
+model_4bit = AutoModelForCausalLM.from_pretrained(
+ model_name, device_map="auto", load_in_4bit=True, max_memory=max_memory_mapping
+)
+```
+이 예에서는 첫 번째 GPU가 600MB의 메모리를 사용하고 두 번째 GPU가 1GB를 사용합니다.
+
+### 고급 사용법 [[advanced-usage]]
+
+이 방법의 더 고급 사용법에 대해서는 [양자화](main_classes/quantization) 문서 페이지를 참조하세요.
+
+## Int8 혼합 정밀도 행렬 분해를 위한 `bitsandbytes` 통합 [[bitsandbytes-integration-for-int8-mixedprecision-matrix-decomposition]]
+
+
+
+이 기능은 다중 GPU 설정에서도 사용할 수 있습니다.
+
+
+
+[`LLM.int8() : 8-bit Matrix Multiplication for Transformers at Scale`](https://arxiv.org/abs/2208.07339) 논문에서 우리는 몇 줄의 코드로 Hub의 모든 모델에 대한 Hugging Face 통합을 지원합니다.
+이 방법은 `float16` 및 `bfloat16` 가중치에 대해 `nn.Linear` 크기를 2배로 줄이고, `float32` 가중치에 대해 4배로 줄입니다. 이는 절반 정밀도에서 이상치를 처리함으로써 품질에 거의 영향을 미치지 않습니다.
+
+
+
+Int8 혼합 정밀도 행렬 분해는 행렬 곱셈을 두 개의 스트림으로 분리합니다: (1) fp16로 곱해지는 체계적인 특이값 이상치 스트림 행렬(0.01%) 및 (2) int8 행렬 곱셈의 일반적인 스트림(99.9%). 이 방법을 사용하면 매우 큰 모델에 대해 예측 저하 없이 int8 추론이 가능합니다.
+이 방법에 대한 자세한 내용은 [논문](https://arxiv.org/abs/2208.07339)이나 [통합에 관한 블로그 글](https://huggingface.co/blog/hf-bitsandbytes-integration)에서 확인할 수 있습니다.
+
+
+
+커널은 GPU 전용으로 컴파일되어 있기 때문에 혼합 8비트 모델을 실행하려면 GPU가 필요합니다. 이 기능을 사용하기 전에 모델의 1/4(또는 모델 가중치가 절반 정밀도인 경우 절반)을 저장할 충분한 GPU 메모리가 있는지 확인하세요.
+이 모듈을 사용하는 데 도움이 되는 몇 가지 참고 사항이 아래에 나와 있습니다. 또는 [Google colab](#colab-demos)에서 데모를 따라할 수도 있습니다.
+
+### 요구 사항 [[requirements-for-int8-mixedprecision-matrix-decomposition]]
+
+- `bitsandbytes<0.37.0`을 사용하는 경우, 8비트 텐서 코어(Turing, Ampere 또는 이후 아키텍처 - 예: T4, RTX20s RTX30s, A40-A100)를 지원하는 NVIDIA GPU에서 실행하는지 확인하세요. `bitsandbytes>=0.37.0`을 사용하는 경우, 모든 GPU가 지원됩니다.
+- 올바른 버전의 `bitsandbytes`를 다음 명령으로 설치하세요:
+`pip install bitsandbytes>=0.31.5`
+- `accelerate`를 설치하세요
+`pip install accelerate>=0.12.0`
+
+### 혼합 Int8 모델 실행 - 단일 GPU 설정 [[running-mixedint8-models-single-gpu-setup]]
+
+필요한 라이브러리를 설치한 후 혼합 8비트 모델을 가져오는 방법은 다음과 같습니다:
+
+```py
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+model_name = "bigscience/bloom-2b5"
+model_8bit = AutoModelForCausalLM.from_pretrained(model_name, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+```
+
+텍스트 생성의 경우:
+
+* `pipeline()` 함수 대신 모델의 `generate()` 메소드를 사용하는 것을 권장합니다. `pipeline()` 함수로는 추론이 가능하지만, 혼합 8비트 모델에 최적화되지 않았기 때문에 `generate()` 메소드를 사용하는 것보다 느릴 수 있습니다. 또한, nucleus 샘플링과 같은 일부 샘플링 전략은 혼합 8비트 모델에 대해 `pipeline()` 함수에서 지원되지 않습니다.
+* 입력을 모델과 동일한 GPU에 배치하는 것이 좋습니다.
+
+다음은 간단한 예입니다:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+model_name = "bigscience/bloom-2b5"
+tokenizer = AutoTokenizer.from_pretrained(model_name)
+model_8bit = AutoModelForCausalLM.from_pretrained(model_name, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+
+prompt = "Hello, my llama is cute"
+inputs = tokenizer(prompt, return_tensors="pt").to("cuda")
+generated_ids = model.generate(**inputs)
+outputs = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+```
+
+
+### 혼합 Int8 모델 실행 - 다중 GPU 설정 [[running-mixedint8-models-multi-gpu-setup]]
+
+다중 GPU에서 혼합 8비트 모델을 로드하는 방법은 단일 GPU 설정과 동일합니다(동일한 명령어 사용):
+```py
+model_name = "bigscience/bloom-2b5"
+model_8bit = AutoModelForCausalLM.from_pretrained(model_name, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+```
+하지만 `accelerate`를 사용하여 각 GPU에 할당할 GPU RAM을 제어할 수 있습니다. 다음과 같이 `max_memory` 인수를 사용하세요:
+
+```py
+max_memory_mapping = {0: "1GB", 1: "2GB"}
+model_name = "bigscience/bloom-3b"
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ model_name, device_map="auto", load_in_8bit=True, max_memory=max_memory_mapping
+)
+```
+이 예시에서는 첫 번째 GPU가 1GB의 메모리를 사용하고 두 번째 GPU가 2GB를 사용합니다.
+
+### Colab 데모 [[colab-demos]]
+
+이 방법을 사용하면 이전에 Google Colab에서 추론할 수 없었던 모델에 대해 추론할 수 있습니다.
+Google Colab에서 8비트 양자화를 사용하여 T5-11b(42GB in fp32)를 실행하는 데모를 확인하세요:
+
+[](https://colab.research.google.com/drive/1YORPWx4okIHXnjW7MSAidXN29mPVNT7F?usp=sharing)
+
+또는 BLOOM-3B에 대한 데모를 확인하세요:
+
+[](https://colab.research.google.com/drive/1qOjXfQIAULfKvZqwCen8-MoWKGdSatZ4?usp=sharing)
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_train_cpu.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_train_cpu.md
new file mode 100644
index 0000000000000000000000000000000000000000..1a6c58b25afae10db053e7ae94b7f5c36c75fb7a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_train_cpu.md
@@ -0,0 +1,67 @@
+
+
+# CPU에서 효율적인 훈련 [[efficient-training-on-cpu]]
+
+이 가이드는 CPU에서 대규모 모델을 효율적으로 훈련하는 데 초점을 맞춥니다.
+
+## IPEX와 혼합 정밀도 [[mixed-precision-with-ipex]]
+
+IPEX는 AVX-512 이상을 지원하는 CPU에 최적화되어 있으며, AVX2만 지원하는 CPU에도 기능적으로 작동합니다. 따라서 AVX-512 이상의 Intel CPU 세대에서는 성능상 이점이 있을 것으로 예상되지만, AVX2만 지원하는 CPU (예: AMD CPU 또는 오래된 Intel CPU)의 경우에는 IPEX 아래에서 더 나은 성능을 보일 수 있지만 이는 보장되지 않습니다. IPEX는 Float32와 BFloat16를 모두 사용하여 CPU 훈련을 위한 성능 최적화를 제공합니다. BFloat16의 사용은 다음 섹션의 주요 초점입니다.
+
+저정밀도 데이터 타입인 BFloat16은 3세대 Xeon® Scalable 프로세서 (코드명: Cooper Lake)에서 AVX512 명령어 집합을 네이티브로 지원해 왔으며, 다음 세대의 Intel® Xeon® Scalable 프로세서에서 Intel® Advanced Matrix Extensions (Intel® AMX) 명령어 집합을 지원하여 성능을 크게 향상시킬 예정입니다. CPU 백엔드의 자동 혼합 정밀도 기능은 PyTorch-1.10부터 활성화되었습니다. 동시에, Intel® Extension for PyTorch에서 BFloat16에 대한 CPU의 자동 혼합 정밀도 및 연산자의 BFloat16 최적화를 대규모로 활성화하고, PyTorch 마스터 브랜치로 부분적으로 업스트림을 반영했습니다. 사용자들은 IPEX 자동 혼합 정밀도를 사용하여 더 나은 성능과 사용자 경험을 얻을 수 있습니다.
+
+[자동 혼합 정밀도](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/features/amp.html)에 대한 자세한 정보를 확인하십시오.
+
+### IPEX 설치: [[ipex-installation]]
+
+IPEX 릴리스는 PyTorch를 따라갑니다. pip를 통해 설치하려면:
+
+| PyTorch Version | IPEX version |
+| :---------------: | :----------: |
+| 1.13 | 1.13.0+cpu |
+| 1.12 | 1.12.300+cpu |
+| 1.11 | 1.11.200+cpu |
+| 1.10 | 1.10.100+cpu |
+
+```bash
+pip install intel_extension_for_pytorch== -f https://developer.intel.com/ipex-whl-stable-cpu
+```
+
+[IPEX 설치](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/installation.html)에 대한 더 많은 접근 방법을 확인하십시오.
+
+### Trainer에서의 사용법 [[usage-in-trainer]]
+Trainer에서 IPEX의 자동 혼합 정밀도를 활성화하려면 사용자는 훈련 명령 인수에 `use_ipex`, `bf16`, `no_cuda`를 추가해야 합니다.
+
+[Transformers 질문-응답](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)의 사용 사례를 살펴보겠습니다.
+
+- CPU에서 BF16 자동 혼합 정밀도를 사용하여 IPEX로 훈련하기:
+ python run_qa.py \
+--model_name_or_path google-bert/bert-base-uncased \
+--dataset_name squad \
+--do_train \
+--do_eval \
+--per_device_train_batch_size 12 \
+--learning_rate 3e-5 \
+--num_train_epochs 2 \
+--max_seq_length 384 \
+--doc_stride 128 \
+--output_dir /tmp/debug_squad/ \
+--use_ipex \
+--bf16 --no_cuda
+
+### 실습 예시 [[practice-example]]
+
+블로그: [Intel Sapphire Rapids로 PyTorch Transformers 가속화](https://huggingface.co/blog/intel-sapphire-rapids)
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_train_cpu_many.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_train_cpu_many.md
new file mode 100644
index 0000000000000000000000000000000000000000..e7a68971a7dc54e465dfbefb3290a5a46daf0524
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_train_cpu_many.md
@@ -0,0 +1,134 @@
+
+
+# 다중 CPU에서 효율적으로 훈련하기 [[efficient-training-on-multiple-cpus]]
+
+하나의 CPU에서 훈련하는 것이 너무 느릴 때는 다중 CPU를 사용할 수 있습니다. 이 가이드는 PyTorch 기반의 DDP를 사용하여 분산 CPU 훈련을 효율적으로 수행하는 방법에 대해 설명합니다.
+
+## PyTorch용 Intel® oneCCL 바인딩 [[intel-oneccl-bindings-for-pytorch]]
+
+[Intel® oneCCL](https://github.com/oneapi-src/oneCCL) (collective communications library)은 allreduce, allgather, alltoall과 같은 집합 통신(collective communications)을 구현한 효율적인 분산 딥러닝 훈련을 위한 라이브러리입니다. oneCCL에 대한 자세한 정보는 [oneCCL 문서](https://spec.oneapi.com/versions/latest/elements/oneCCL/source/index.html)와 [oneCCL 사양](https://spec.oneapi.com/versions/latest/elements/oneCCL/source/index.html)을 참조하세요.
+
+`oneccl_bindings_for_pytorch` 모듈 (`torch_ccl`은 버전 1.12 이전에 사용)은 PyTorch C10D ProcessGroup API를 구현하며, 외부 ProcessGroup로 동적으로 가져올 수 있으며 현재 Linux 플랫폼에서만 작동합니다.
+
+[oneccl_bind_pt](https://github.com/intel/torch-ccl)에서 더 자세한 정보를 확인하세요.
+
+### PyTorch용 Intel® oneCCL 바인딩 설치: [[intel-oneccl-bindings-for-pytorch-installation]]
+
+다음 Python 버전에 대한 Wheel 파일을 사용할 수 있습니다.
+
+| Extension Version | Python 3.6 | Python 3.7 | Python 3.8 | Python 3.9 | Python 3.10 |
+| :---------------: | :--------: | :--------: | :--------: | :--------: | :---------: |
+| 1.13.0 | | √ | √ | √ | √ |
+| 1.12.100 | | √ | √ | √ | √ |
+| 1.12.0 | | √ | √ | √ | √ |
+| 1.11.0 | | √ | √ | √ | √ |
+| 1.10.0 | √ | √ | √ | √ | |
+
+```bash
+pip install oneccl_bind_pt=={pytorch_version} -f https://developer.intel.com/ipex-whl-stable-cpu
+```
+`{pytorch_version}`은 1.13.0과 같이 PyTorch 버전을 나타냅니다.
+[oneccl_bind_pt 설치](https://github.com/intel/torch-ccl)에 대한 더 많은 접근 방법을 확인해 보세요.
+oneCCL과 PyTorch의 버전은 일치해야 합니다.
+
+
+
+oneccl_bindings_for_pytorch 1.12.0 버전의 미리 빌드된 Wheel 파일은 PyTorch 1.12.1과 호환되지 않습니다(PyTorch 1.12.0용입니다).
+PyTorch 1.12.1은 oneccl_bindings_for_pytorch 1.12.10 버전과 함께 사용해야 합니다.
+
+
+
+## Intel® MPI 라이브러리 [[intel-mpi-library]]
+이 표준 기반 MPI 구현을 사용하여 Intel® 아키텍처에서 유연하고 효율적이며 확장 가능한 클러스터 메시징을 제공하세요. 이 구성 요소는 Intel® oneAPI HPC Toolkit의 일부입니다.
+
+oneccl_bindings_for_pytorch는 MPI 도구 세트와 함께 설치됩니다. 사용하기 전에 환경을 소스로 지정해야 합니다.
+
+Intel® oneCCL 버전 1.12.0 이상인 경우
+```bash
+oneccl_bindings_for_pytorch_path=$(python -c "from oneccl_bindings_for_pytorch import cwd; print(cwd)")
+source $oneccl_bindings_for_pytorch_path/env/setvars.sh
+```
+
+Intel® oneCCL 버전이 1.12.0 미만인 경우
+```bash
+torch_ccl_path=$(python -c "import torch; import torch_ccl; import os; print(os.path.abspath(os.path.dirname(torch_ccl.__file__)))")
+source $torch_ccl_path/env/setvars.sh
+```
+
+#### IPEX 설치: [[ipex-installation]]
+
+IPEX는 Float32와 BFloat16을 모두 사용하는 CPU 훈련을 위한 성능 최적화를 제공합니다. [single CPU section](./perf_train_cpu)을 참조하세요.
+
+
+이어서 나오는 "Trainer에서의 사용"은 Intel® MPI 라이브러리의 mpirun을 예로 들었습니다.
+
+
+## Trainer에서의 사용 [[usage-in-trainer]]
+Trainer에서 ccl 백엔드를 사용하여 멀티 CPU 분산 훈련을 활성화하려면 명령 인수에 **`--ddp_backend ccl`**을 추가해야 합니다.
+
+[질의 응답 예제](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)를 사용한 예를 살펴보겠습니다.
+
+
+다음 명령은 한 Xeon 노드에서 2개의 프로세스로 훈련을 활성화하며, 각 소켓당 하나의 프로세스가 실행됩니다. OMP_NUM_THREADS/CCL_WORKER_COUNT 변수는 최적의 성능을 위해 조정할 수 있습니다.
+```shell script
+ export CCL_WORKER_COUNT=1
+ export MASTER_ADDR=127.0.0.1
+ mpirun -n 2 -genv OMP_NUM_THREADS=23 \
+ python3 run_qa.py \
+ --model_name_or_path google-bert/bert-large-uncased \
+ --dataset_name squad \
+ --do_train \
+ --do_eval \
+ --per_device_train_batch_size 12 \
+ --learning_rate 3e-5 \
+ --num_train_epochs 2 \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir /tmp/debug_squad/ \
+ --no_cuda \
+ --ddp_backend ccl \
+ --use_ipex
+```
+다음 명령은 두 개의 Xeon(노드0 및 노드1, 주 프로세스로 노드0을 사용)에서 총 4개의 프로세스로 훈련을 활성화하며, 각 소켓당 하나의 프로세스가 실행됩니다. OMP_NUM_THREADS/CCL_WORKER_COUNT 변수는 최적의 성능을 위해 조정할 수 있습니다.
+
+노드0에서는 각 노드의 IP 주소를 포함하는 구성 파일(예: hostfile)을 생성하고 해당 구성 파일 경로를 인수로 전달해야 합니다.
+```shell script
+ cat hostfile
+ xxx.xxx.xxx.xxx #node0 ip
+ xxx.xxx.xxx.xxx #node1 ip
+```
+이제 노드0에서 다음 명령을 실행하면 **4DDP**가 노드0 및 노드1에서 BF16 자동 혼합 정밀도로 활성화됩니다.
+```shell script
+ export CCL_WORKER_COUNT=1
+ export MASTER_ADDR=xxx.xxx.xxx.xxx #node0 ip
+ mpirun -f hostfile -n 4 -ppn 2 \
+ -genv OMP_NUM_THREADS=23 \
+ python3 run_qa.py \
+ --model_name_or_path google-bert/bert-large-uncased \
+ --dataset_name squad \
+ --do_train \
+ --do_eval \
+ --per_device_train_batch_size 12 \
+ --learning_rate 3e-5 \
+ --num_train_epochs 2 \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir /tmp/debug_squad/ \
+ --no_cuda \
+ --ddp_backend ccl \
+ --use_ipex \
+ --bf16
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_train_gpu_many.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_train_gpu_many.md
new file mode 100644
index 0000000000000000000000000000000000000000..c2a80505ef7659d0069fbc9d1c1ef36d29fd5378
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_train_gpu_many.md
@@ -0,0 +1,533 @@
+
+
+# 다중 GPU에서 효율적인 훈련 [[efficient-training-on-multiple-gpus]]
+
+단일 GPU에서의 훈련이 너무 느리거나 모델 가중치가 단일 GPU의 메모리에 맞지 않는 경우, 다중-GPU 설정을 사용합니다. 단일 GPU에서 다중 GPU로 전환하기 위해서는 작업을 분산해야 합니다. 데이터, 텐서 또는 파이프라인과 같은 병렬화 기법을 사용하여 작업을 병렬로 처리할 수 있습니다. 그러나 이러한 설정을 모두에게 적용할 수 있는 완벽한 해결책은 없으며, 어떤 설정이 가장 적합한지는 사용하는 하드웨어에 따라 달라집니다. 이 문서는 주로 PyTorch 기반의 구현을 중심으로 설명하며, 대부분의 개념은 다른 프레임워크에도 적용될 수 있을 것으로 예상됩니다.
+
+
+
+ 참고: [단일 GPU 섹션](perf_train_gpu_one)에서 소개된 전략(혼합 정밀도 훈련 또는 그래디언트 누적 등)은 일반적으로 모델 훈련에 적용되며, 다중-GPU 또는 CPU 훈련과 같은 다음 섹션으로 진입하기 전에 해당 섹션을 참고하는 것이 좋습니다.
+
+
+
+먼저 1D 병렬화 기술에 대해 자세히 논의한 후, 이러한 기술을 결합하여 2D 및 3D 병렬화를 구현하여 더 빠른 훈련과 더 큰 모델을 지원하는 방법을 살펴볼 것입니다. 또한 다른 효과적인 대안 방식도 소개될 예정입니다.
+
+## 개념 [[concepts]]
+
+다음은 이 문서에서 자세히 설명될 주요 개념에 대한 간단한 설명입니다.
+
+1. **DataParallel (DP)** - 동일한 설정이 여러 번 복제되고, 각 설정에 데이터 일부를 받습니다. 처리는 병렬로 수행되며 모든 설정은 각 훈련 단계의 끝날 때 동기화됩니다.
+2. **TensorParallel (TP)** - 각 텐서는 여러 개의 묶음으로 분할되기에, 전체 텐서가 단일 GPU에 상주하는 대신 텐서의 각 샤드가 지정된 GPU에 상주합니다. 처리하는 동안 각 샤드는 서로 다른 GPU에서 개별적으로 병렬 처리되며 결과는 단계가 끝날 때 동기화됩니다. 분할이 수평 수준에서 이루어지기 때문에 이를 수평 병렬 처리라고 부를 수 있습니다.
+3. **PipelineParallel (PP)** - 모델이 수직으로 (레이어 수준) 여러 GPU에 분할되어 모델의 단일 GPU에는 하나 또는 여러 레이어가 배치됩니다. 각 GPU는 파이프라인의 서로 다른 단계를 병렬로 처리하며 작은 배치 묶음에서 작동합니다.
+4. **Zero Redundancy Optimizer (ZeRO)** - TP와 유사하게 텐서를 샤딩하지만, 전체 텐서는 순방향 또는 역방향 계산을 위해 재구성되므로 모델을 수정할 필요가 없습니다. 또한 제한된 GPU 메모리를 보완하기 위해 다양한 오프로드 기술을 지원합니다.
+5. **Sharded DDP** - ZeRO의 기본 개념으로 다른 ZeRO 구현에서도 사용되는 용어입니다.
+
+각 개념의 구체적인 내용에 대해 자세히 들어가기 전에 대규모 인프라에서 대규모 모델을 훈련하는 경우의 대략적인 결정 과정을 살펴보겠습니다.
+
+## 확장성 전략 [[scalability-strategy]]
+
+**⇨ 단일 노드 / 다중-GPU**
+* 모델이 단일 GPU에 맞는 경우:
+
+ 1. DDP - 분산 DP
+ 2. ZeRO - 상황과 구성에 따라 더 빠를 수도 있고 그렇지 않을 수도 있음
+
+* 모델이 단일 GPU에 맞지 않는 경우:
+
+ 1. PP
+ 2. ZeRO
+ 3. TP
+
+ 노드 내 연결 속도가 매우 빠른 NVLINK 또는 NVSwitch의 경우 세 가지 방법은 대부분 비슷한 성능을 보여야 하며, PP가 없는 경우 TP 또는 ZeRO보다 빠를 것입니다. TP의 정도도 차이를 만들 수 있습니다. 특정 설정에서 승자를 찾기 위해 실험하는 것이 가장 좋습니다.
+
+ TP는 거의 항상 단일 노드 내에서 사용됩니다. 즉, TP 크기 <= 노드당 GPU 수입니다.
+
+* 가장 큰 레이어가 단일 GPU에 맞지 않는 경우:
+
+ 1. ZeRO를 사용하지 않는 경우 - PP만으로는 맞지 않으므로 TP를 반드시 사용해야 함
+ 2. ZeRO를 사용하는 경우에는 위의 "단일 GPU" 항목과 동일
+
+
+**⇨ 다중 노드 / 다중 GPU**
+
+* 노드 간 연결 속도가 빠른 경우:
+
+ 1. ZeRO - 모델에 대부분의 수정을 필요로 하지 않음
+ 2. PP+TP+DP - 통신이 적지만 모델에 대대적인 변경이 필요함
+
+* 노드 간 연결 속도가 느리며, GPU 메모리가 여전히 부족한 경우:
+
+ 1. DP+PP+TP+ZeRO-1
+
+
+
+## 데이터 병렬화 [[data-parallelism]]
+
+2개의 GPU만으로도 대부분의 사용자들은 `DataParallel` (DP)과 `DistributedDataParallel` (DDP)을 통해 향상된 훈련 속도를 누릴 수 있습니다. 이는 PyTorch의 내장 기능입니다. 일반적으로 DDP를 사용하는 것이 좋으며, DP는 일부 모델에서 작동하지 않을 수 있으므로 주의해야 합니다. [PyTorch 문서](https://pytorch.org/docs/master/generated/torch.nn.DataParallel.html)에서도 DDP의 사용을 권장합니다.
+
+### DP vs DDP [[dp-vs-ddp]]
+
+`DistributedDataParallel` (DDP)은 일반적으로 `DataParallel` (DP)보다 빠르지만, 항상 그렇지는 않습니다:
+* DP는 파이썬 스레드 기반인 반면, DDP는 다중 프로세스 기반이기 때문에 GIL과 같은 파이썬 스레드 제한이 없습니다.
+* 그러나 GPU 카드 간의 느린 상호 연결성은 DDP로 인해 실제로 느린 결과를 낼 수 있습니다.
+
+이 두 모드 간의 GPU 간 통신 오버헤드의 주요 차이점은 다음과 같습니다:
+
+[DDP](https://pytorch.org/docs/master/notes/ddp.html):
+
+- 시작할 때, 주 프로세스가 모델을 gpu 0에서 다른 모든 gpu로 복제합니다.
+- 그런 다음 각 배치에 대해:
+ 1. 각 gpu는 자체 미니 배치 데이터를 직접 사용합니다.
+ 2. `backward` 동안 로컬 그래디언트가 준비되면, 모든 프로세스에 평균화됩니다.
+
+[DP](https://pytorch.org/docs/master/generated/torch.nn.DataParallel.html):
+
+각 배치에 대해:
+ 1. gpu 0은 데이터 배치를 읽고 각 gpu에 미니 배치를 보냅니다.
+ 2. 업데이트된 모델을 gpu 0에서 각 gpu로 복제합니다.
+ 3. `forward`를 실행하고 각 gpu의 출력을 gpu 0으로 보내고 손실을 계산합니다.
+ 4. gpu 0에서 모든 gpu로 손실을 분산하고 `backward`를 실행합니다.
+ 5. 각 gpu에서 그래디언트를 gpu 0으로 보내고 이를 평균화합니다.
+
+DDP는 각 배치마다 그래디언트를 보내는 통신만을 수행하며, DP는 배치마다 5개의 다른 데이터 교환을 수행합니다.
+
+DP는 파이썬 스레드를 통해 프로세스 내에서 데이터를 복제하며, DDP는 [torch.distributed](https://pytorch.org/docs/master/distributed.html)를 통해 데이터를 복제합니다.
+
+DP에서는 gpu 0이 다른 gpu보다 훨씬 더 많은 작업을 수행하므로, gpu의 활용도가 낮아집니다.
+
+DDP는 여러 대의 컴퓨터에서 사용할 수 있지만, DP의 경우는 그렇지 않습니다.
+
+DP와 DDP 사이에는 다른 차이점이 있지만, 이 토론과는 관련이 없습니다.
+
+이 2가지 모드를 깊게 이해하고 싶다면, [이 문서](https://www.telesens.co/2019/04/04/distributed-data-parallel-training-using-pytorch-on-aws/)를 강력히 추천합니다. 이 문서는 멋진 다이어그램을 포함하고 있으며, 다양한 하드웨어에서 여러 벤치마크와 프로파일러 출력을 설명하여 필요한 세부 사항을 모두 설명합니다.
+
+실제 벤치마크를 살펴보겠습니다:
+
+| Type | NVlink | Time |
+| :----- | ----- | ---: |
+| 2:DP | Y | 110s |
+| 2:DDP | Y | 101s |
+| 2:DDP | N | 131s |
+
+
+분석:
+
+여기서 DP는 NVlink가 있는 DDP보다 약 10% 느립니다. 그러나 NVlink가 없는 DDP보다 약 15% 빠릅니다.
+
+실제 차이는 각 GPU가 다른 GPU와 동기화해야 하는 데이터 양에 따라 달라질 것입니다. 동기화할 데이터가 많을수록 느린 링크가 총 실행 시간을 늦출 수 있습니다.
+
+다음은 전체 벤치마크 코드와 출력입니다:
+
+해당 벤치마크에서 `NCCL_P2P_DISABLE=1`을 사용하여 NVLink 기능을 비활성화했습니다.
+
+```bash
+
+# DP
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 \
+python examples/pytorch/language-modeling/run_clm.py \
+--model_name_or_path openai-community/gpt2 --dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 \
+--do_train --output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 110.5948, 'train_samples_per_second': 1.808, 'epoch': 0.69}
+
+# DDP w/ NVlink
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 \
+torchrun --nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py \
+--model_name_or_path openai-community/gpt2 --dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 \
+--do_train --output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 101.9003, 'train_samples_per_second': 1.963, 'epoch': 0.69}
+
+# DDP w/o NVlink
+rm -r /tmp/test-clm; NCCL_P2P_DISABLE=1 CUDA_VISIBLE_DEVICES=0,1 \
+torchrun --nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py \
+--model_name_or_path openai-community/gpt2 --dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 \
+--do_train --output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 131.4367, 'train_samples_per_second': 1.522, 'epoch': 0.69}
+```
+
+하드웨어: 각각 24GB의 TITAN RTX 2개 + NVlink과 2개의 NVLink (`nvidia-smi topo -m`에서 `NV2`입니다.)
+소프트웨어: `pytorch-1.8-to-be` + `cuda-11.0` / `transformers==4.3.0.dev0`
+
+## ZeRO 데이터 병렬화 [[zero-data-parallelism]]
+
+ZeRO를 기반으로 한 데이터 병렬화 (ZeRO-DP)는 다음 [블로그 글](https://www.microsoft.com/en-us/research/blog/zero-deepspeed-new-system-optimizations-enable-training-models-with-over-100-billion-parameters/)의 다음 다이어그램에서 설명되고 있습니다.
+
+
+이 개념은 이해하기 어려울 수 있지만, 실제로는 매우 간단한 개념입니다. 이는 일반적인 `DataParallel` (DP)과 동일하지만, 전체 모델 매개변수, 그래디언트 및 옵티마이저 상태를 복제하는 대신 각 GPU는 그 중 일부만 저장합니다. 그리고 실행 시간에는 주어진 레이어에 대해 전체 레이어 매개변수가 필요할 때 각 GPU가 서로에게 필요한 부분을 제공하기 위해 동기화됩니다 - 그게 전부입니다.
+
+각각 3개의 레이어와 3개의 매개변수가 있는 간단한 모델을 생각해 봅시다:
+```
+La | Lb | Lc
+---|----|---
+a0 | b0 | c0
+a1 | b1 | c1
+a2 | b2 | c2
+```
+레이어 La에는 가중치 a0, a1 및 a2가 있습니다.
+
+3개의 GPU가 있는 경우, Sharded DDP (= Zero-DP)는 다음과 같이 모델을 3개의 GPU에 분할합니다:
+
+```
+GPU0:
+La | Lb | Lc
+---|----|---
+a0 | b0 | c0
+
+GPU1:
+La | Lb | Lc
+---|----|---
+a1 | b1 | c1
+
+GPU2:
+La | Lb | Lc
+---|----|---
+a2 | b2 | c2
+```
+
+일반적인 DNN 다이어그램을 상상해보면 이는 텐서 병렬 처리와 같은 수평 슬라이싱입니다. 수직 슬라이싱은 전체 레이어 그룹을 다른 GPU에 배치하는 것입니다. 이는 시작에 불과합니다.
+
+이제 이러한 각각의 GPU는 DP에서 작동하는 것과 마찬가지로 일반적인 미니 배치를 받습니다:
+```
+x0 => GPU0
+x1 => GPU1
+x2 => GPU2
+```
+
+입력은 수정되지 않은 상태로 일반 모델에 의해 처리될 것으로 간주합니다.
+
+먼저, 입력은 레이어 La에 도달합니다.
+
+GPU0에만 집중해 보겠습니다. x0은 순방향 경로를 수행하기 위해 a0, a1, a2 파라미터가 필요하지만 GPU0에는 a0만 있습니다. GPU1에서 a1을, GPU2에서 a2를 전송받아 모델의 모든 조각을 하나로 모읍니다.
+
+병렬적으로, GPU1은 미니 배치 x1을 받고 a1만 가지고 있지만, a0 및 a2 매개변수가 필요합니다. 따라서 GPU0 및 GPU2에서 이를 가져옵니다.
+
+GPU2도 동일한 작업을 수행합니다. 입력 x2를 받고 GPU0 및 GPU1에서 각각 a0과 a1을, 그리고 자신의 a2와 함께 전체 텐서를 복원합니다.
+
+3개의 GPU는 복원된 전체 텐서를 받고 forward가 수행됩니다.
+
+계산이 완료되면 더 이상 필요하지 않은 데이터는 삭제되고, 해당 데이터는 계산 중에만 사용됩니다. 복원은 사전 패치를 통해 효율적으로 수행됩니다.
+
+그리고 전체 프로세스는 레이어 Lb에 대해 반복되고, 그 다음 Lc로 순방향으로, 그다음은 역방향으로 Lc -> Lb -> La로 반복됩니다.
+
+개인적으로 이것은 효율적인 그룹 배낭 여행자의 중량 분배 전략처럼 들립니다:
+
+1. 사람 A가 텐트를 운반합니다.
+2. 사람 B가 난로를 운반합니다.
+3. 사람 C가 도끼를 운반합니다.
+
+이제 매일 밤 각자 가진 것을 다른 사람들과 공유하고, 가지지 않은 것은 다른 사람들로부터 받고, 아침에는 할당된 유형의 장비를 싸고 계속해서 여행을 진행합니다. 이것이 Sharded DDP / Zero DP입니다.
+
+이 전략을 각각 자신의 텐트, 난로 및 도끼를 개별적으로 운반해야 하는 단순한 전략과 비교해보면 훨씬 비효율적일 것입니다. 이것이 Pytorch의 DataParallel (DP 및 DDP)입니다.
+
+이 주제에 대해 논문을 읽을 때 다음 동의어를 만날 수 있습니다: Sharded, Partitioned.
+
+ZeRO가 모델 가중치를 분할하는 방식을 자세히 살펴보면, 텐서 병렬화와 매우 유사한 것을 알 수 있습니다. 이는 이후에 설명될 수직 모델 병렬화와는 달리 각 레이어의 가중치를 분할/분할하기 때문입니다.
+
+구현:
+
+- [DeepSpeed](https://www.deepspeed.ai/tutorials/zero/)는 1단계 + 2단계 + 3단계의 ZeRO-DP를 제공합니다.
+- [Fairscale](https://github.com/facebookresearch/fairscale/#optimizer-state-sharding-zero)은 1단계 + 2단계 + 3단계의 ZeRO-DP를 제공합니다.
+- [`transformers` 통합](main_classes/trainer#trainer-integrations)
+
+## 네이티브 모델 병렬 처리(수직적) 및 파이프라인 병렬 처리[[naive-model-parallelism-vertical-and-pipeline-parallelism]]
+
+Naive Model Parallelism (MP)은 모델 레이어 그룹을 다중 GPU에 분산하는 방식입니다. 메커니즘은 상대적으로 간단합니다. 원하는 레이어를 `.to()`를 사용하여 원하는 장치로 전환하면 데이터가 해당 레이어로 들어오고 나갈 때 데이터도 레이어와 동일한 장치로 전환되고 나머지는 수정되지 않습니다.
+
+대부분의 모델이 그려지는 방식이 레이어를 세로로 슬라이스하기 때문에 이를 수직 모델 병렬화라고 부릅니다. 예를 들어 다음 다이어그램은 8레이어 모델을 보여줍니다:
+
+```
+=================== ===================
+| 0 | 1 | 2 | 3 | | 4 | 5 | 6 | 7 |
+=================== ===================
+ gpu0 gpu1
+```
+우리는 모델을 수직으로 2개로 분할하여 레이어 0-3을 GPU0에 배치하고 레이어 4-7을 GPU1에 배치했습니다.
+
+이제 데이터가 레이어 0에서 1로, 1에서 2로, 2에서 3으로 이동하는 동안에는 일반적인 모델입니다. 그러나 데이터가 레이어 3에서 레이어 4로 전달되어야 할 때는 GPU0에서 GPU1로 이동해야 하므로 통신 오버헤드가 발생합니다. 참여하는 GPU가 동일한 컴퓨팅 노드(예: 동일한 물리적인 기계)에 있는 경우 이 복사는 매우 빠릅니다. 그러나 GPU가 서로 다른 컴퓨팅 노드(예: 여러 기계)에 위치한 경우 통신 오버헤드는 상당히 크게 될 수 있습니다.
+
+그런 다음 레이어 4부터 5로, 6으로, 7로 진행되는 것은 일반적인 모델과 동일하게 진행되고, 7번째 레이어가 완료되면 데이터를 다시 레이어 0으로 보내거나 또는 레이블을 마지막 레이어로 보내야 할 필요가 있습니다. 이제 손실을 계산하고 옵티마이저가 작동할 수 있습니다.
+
+문제점:
+- 이 방식을 "naive" MP라고 부르는 이유는 주어진 상황에 하나의 GPU를 제외한 모든 GPU가 유휴 상태라는 점입니다. 따라서 4개의 GPU를 사용하는 경우 단일 GPU의 메모리 양을 4배로 늘리고 나머지 하드웨어는 무시하는 것과 거의 동일합니다. 또한 장치 간 데이터 복사의 오버헤드도 있습니다. 따라서 4개의 6GB 카드는 naive MP를 사용하여 1개의 24GB 카드와 동일한 크기를 수용할 수 있지만, 후자는 데이터 복사의 오버헤드가 없으므로 훈련을 더 빨리 완료합니다. 그러나 예를 들어 40GB 카드가 있고 45GB 모델을 맞추어야 할 경우 4개의 40GB 카드로 맞출 수 있습니다 (하지만 그래디언트와 옵티마이저 상태 때문에 가까스로 가능합니다).
+- 공유 임베딩은 GPU 간에 복사해야 할 수도 있습니다.
+
+파이프라인 병렬화 (PP)은 거의 naive MP와 동일하지만 GPU 유휴 상태 문제를 해결하기 위해 들어오는 배치를 마이크로 배치로 나누고 인공적으로 파이프라인을 생성하여 서로 다른 GPU가 동시에 계산에 참여할 수 있게 합니다.
+
+[GPipe 논문](https://ai.googleblog.com/2019/03/introducing-gpipe-open-source-library.html)에서 가져온 그림은 상단에 naive MP를, 하단에는 PP를 보여줍니다:
+
+
+
+하단 다이어그램에서 PP가 유휴 영역이 적은 것을 쉽게 볼 수 있습니다. 유휴 부분을 "bubble"이라고 합니다.
+
+다이어그램의 양쪽 부분은 참여하는 GPU가 4개인 병렬성을 보여줍니다. 즉, 4개의 GPU가 파이프라인에 참여합니다. 따라서 4개의 파이프 단계 F0, F1, F2 및 F3의 순방향 경로와 B3, B2, B1 및 B0의 역방향 경로가 있습니다.
+
+PP는 조정해야 할 새로운 하이퍼파라미터인 `chunks`를 도입합니다. 이는 동일한 파이프 단계를 통해 일련의 데이터를 묶어서 보내는 방식을 정의합니다. 예를 들어, 아래 다이어그램에서 `chunks=4`를 볼 수 있습니다. GPU0은 0, 1, 2 및 3 (F0,0, F0,1, F0,2, F0,3) 묶음에서 동일한 순방향 경로를 수행하고, 다른 GPU가 작업을 수행하기 시작하고 완료가 시작될 때만 GPU0이 묶음의 역순으로 3, 2, 1 및 0 (B0,3, B0,2, B0,1, B0,0) 경로를 수행합니다.
+
+개념적으로 이는 그래디언트 누적 단계 (GAS)와 동일한 개념입니다. 파이토치에서는 `chunks`를 사용하고 DeepSpeed에서는 동일한 하이퍼파라미터를 GAS로 참조합니다.
+
+묶음으로 인해 PP는 마이크로 배치 (MBS)의 개념을 도입합니다. DP는 전역 데이터 배치 크기를 미니 배치로 나눕니다. 따라서 DP 차수가 4이고 전역 배치 크기가 1024이면 256씩 4개의 미니 배치로 분할됩니다 (1024/4). 그리고 `chunks` (또는 GAS)의 수가 32이면 마이크로 배치 크기는 8이 됩니다 (256/32). 각 파이프라인 단계는 한 번에 하나의 마이크로 배치와 함께 작동합니다.
+
+DP + PP 설정의 전역 배치 크기를 계산하려면 `mbs*chunks*dp_degree` (`8*32*4=1024`)를 수행합니다.
+
+다이어그램으로 돌아가 보겠습니다.
+
+`chunks=1`로 설정하면 매우 비효율적인 naive MP가 생성되며, 매우 큰 `chunks` 값으로 설정하면 아주 작은 마이크로 배치 크기가 생성되어 효율적이지 않을 수 있습니다. 따라서 가장 효율적인 GPU 활용을 위해 어떤 값이 가장 적절한지 실험을 해야 합니다.
+
+다이어그램에서 보이는 것처럼 "dead" 시간의 버블이 존재하여 마지막 `forward` 단계가 `backward` 단계가 파이프라인을 완료하기를 기다려야 하는 상황이 발생하지만, `chunks`의 가장 적절한 값을 찾는 것의 목적은 모든 참여하는 GPU에서 동시에 고도로 활용되는 GPU 활용을 가능하게 하여 버블의 크기를 최소화하는 것입니다.
+
+해결책은 전통적인 파이프라인 API와 더 현대적인 솔루션으로 나뉩니다. 전통적인 파이프라인 API 솔루션과 현대적인 솔루션에 대해 알아보겠습니다.
+
+전통적인 파이프라인 API 솔루션:
+- 파이토치
+- FairScale
+- DeepSpeed
+- Megatron-LM
+
+현대적인 솔루션:
+- Varuna
+- Sagemaker
+
+전통적인 파이프라인 API 솔루션의 문제점:
+- 모델을 상당히 수정해야 한다는 점이 문제입니다. 파이프라인은 모듈의 정상적인 흐름을 `nn.Sequential` 시퀀스로 다시 작성해야 하므로 모델의 설계를 변경해야 할 수 있습니다.
+- 현재 파이프라인 API는 매우 제한적입니다. 파이프라인의 매우 첫 번째 단계에서 전달되는 많은 파이썬 변수가 있는 경우 이를 해결해야 합니다. 현재 파이프라인 인터페이스는 하나의 텐서 또는 텐서의 튜플을 유일한 입력 및 출력으로 요구합니다. 이러한 텐서는 마이크로 배치로 미니 배치로 묶을 것이므로 첫 번째 차원으로 배치 크기가 있어야 합니다. 가능한 개선 사항은 여기에서 논의되고 있습니다. https://github.com/pytorch/pytorch/pull/50693
+- 파이프 단계 수준에서 조건부 제어 흐름은 불가능합니다. 예를 들어, T5와 같은 인코더-디코더 모델은 조건부 인코더 단계를 처리하기 위해 특별한 해결책이 필요합니다.
+- 각 레이어를 정렬하여 하나의 모델의 출력이 다른 모델의 입력이 되도록해야 합니다.
+
+우리는 아직 Varuna와 SageMaker로 실험하지 않았지만, 해당 논문들은 위에서 언급한 문제들의 목록을 극복했고 사용자의 모델에 대한 변경 사항이 훨씬 적게 필요하다고 보고하고 있습니다.
+
+구현:
+- [파이토치](https://pytorch.org/docs/stable/pipeline.html) (파이토치-1.8에서 초기 지원, 1.9에서 점진적으로 개선되고 1.10에서 더 개선됨). [예제](https://github.com/pytorch/pytorch/blob/master/benchmarks/distributed/pipeline/pipe.py)도 참고하세요.
+- [FairScale](https://fairscale.readthedocs.io/en/latest/tutorials/pipe.html)
+- [DeepSpeed](https://www.deepspeed.ai/tutorials/pipeline/)
+- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM)은 내부 구현을 가지고 있습니다 - API 없음.
+- [Varuna](https://github.com/microsoft/varuna)
+- [SageMaker](https://arxiv.org/abs/2111.05972) - 이는 AWS에서만 사용할 수 있는 소유 솔루션입니다.
+- [OSLO](https://github.com/tunib-ai/oslo) - 이는 Hugging Face Transformers를 기반으로 구현된 파이프라인 병렬화입니다.
+
+🤗 Transformers 상태: 이 작성 시점에서 모델 중 어느 것도 완전한 PP를 지원하지 않습니다. GPT2와 T5 모델은 naive MP를 지원합니다. 주요 장애물은 모델을 `nn.Sequential`로 변환하고 모든 입력을 텐서로 가져와야 하는 것을 처리할 수 없기 때문입니다. 현재 모델에는 이러한 변환을 매우 복잡하게 만드는 많은 기능이 포함되어 있어 제거해야 합니다.
+
+기타 접근 방법:
+
+DeepSpeed, Varuna 및 SageMaker는 [교차 파이프라인(Interleaved Pipeline)](https://docs.aws.amazon.com/sagemaker/latest/dg/model-parallel-core-features.html) 개념을 사용합니다.
+
+
+여기서는 버블(유휴 시간)을 역방향 패스에 우선순위를 부여하여 최소화합니다.
+
+Varuna는 가장 효율적인 스케줄링을 찾기 위해 시뮬레이션을 사용하여 스케줄을 개선하려고 합니다.
+
+OSLO는 `nn.Sequential`로 변환하지 않고 Transformers를 기반으로 한 파이프라인 병렬화를 구현했습니다.
+
+## 텐서 병렬 처리 [[tensor-parallelism]]
+
+텐서 병렬 처리에서는 각 GPU가 텐서의 일부분만 처리하고 전체 텐서가 필요한 연산에 대해서만 전체 텐서를 집계합니다.
+
+이 섹션에서는 [Megatron-LM](https://github.com/NVIDIA/Megatron-LM) 논문인 [Efficient Large-Scale Language Model Training on GPU Clusters](https://arxiv.org/abs/2104.04473)에서의 개념과 다이어그램을 사용합니다.
+
+Transformer의 주요 구성 요소는 fully connected `nn.Linear`와 비선형 활성화 함수인 `GeLU`입니다.
+
+Megatron 논문의 표기법을 따라 행렬의 점곱 부분을 `Y = GeLU(XA)`로 표현할 수 있습니다. 여기서 `X`와 `Y`는 입력 및 출력 벡터이고 `A`는 가중치 행렬입니다.
+
+행렬 형태로 계산을 살펴보면, 행렬 곱셈을 다중 GPU로 분할할 수 있는 방법을 쉽게 알 수 있습니다:
+
+
+가중치 행렬 `A`를 `N`개의 GPU에 대해 열별로 분할하고 병렬로 행렬 곱셈 `XA_1`에서 `XA_n`까지 수행하면 `N`개의 출력 벡터 `Y_1, Y_2, ..., Y_n`가 생성되며 독립적으로 `GeLU`에 전달될 수 있습니다:
+
+
+이 원리를 사용하여 동기화가 필요하지 않은 GPU 간의 임의 깊이의 MLP를 업데이트할 수 있습니다. 그러나 결과 벡터를 샤드로부터 재구성해야 하는 마지막 단계까지는 GPU 간의 동기화가 필요합니다. Megatron-LM 논문의 저자들은 이에 대한 유용한 그림을 제공합니다:
+
+
+다중 헤드 어텐션 레이어의 병렬화는 더욱 간단합니다. 이미 독립적인 다중 헤드를 가지고 있기 때문에 이미 병렬화되어 있습니다!
+
+
+특별 고려사항: TP는 매우 빠른 네트워크가 필요하므로 한 개 이상의 노드에서 TP를 수행하는 것은 권장되지 않습니다. 실제로 노드에 4개의 GPU가 있는 경우 TP의 최대 차수는 4입니다. TP 차수가 8인 경우 최소한 8개의 GPU가 있는 노드를 사용해야 합니다.
+
+이 섹션은 원래의 [더 자세한 TP 개요](https://github.com/huggingface/transformers/issues/10321#issuecomment-783543530)를 기반으로 합니다.
+작성자는 [@anton-l](https://github.com/anton-l)입니다.
+
+SageMaker는 더 효율적인 처리를 위해 TP와 DP를 결합합니다.
+
+대체 이름:
+- DeepSpeed는 이를 [텐서 슬라이싱](https://www.deepspeed.ai/training/#model-parallelism)이라고 부릅니다.
+
+구현:
+- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM)은 내부 구현을 가지고 있으므로 모델에 매우 특화되어 있습니다.
+- [parallelformers](https://github.com/tunib-ai/parallelformers) (현재는 추론에만 해당)
+- [SageMaker](https://arxiv.org/abs/2111.05972) - 이는 AWS에서만 사용할 수 있는 소유 솔루션입니다.
+- [OSLO](https://github.com/tunib-ai/oslo)은 Transformers를 기반으로 한 텐서 병렬 처리 구현을 가지고 있습니다.
+
+🤗 Transformers 현황:
+- core: 아직 핵심 부분에 구현되지 않음
+- 그러나 추론을 하려면 [parallelformers](https://github.com/tunib-ai/parallelformers)가 대부분의 모델을 지원합니다. 따라서 핵심 부분에 구현되기 전까지 그들의 것을 사용할 수 있습니다. 그리고 훈련 모드도 지원될 예정입니다.
+- Deepspeed-Inference는 CUDA 커널을 기반으로 하는 매우 빠른 추론 모드에서 BERT, GPT-2 및 GPT-Neo 모델을 지원합니다. 자세한 내용은 [여기](https://www.deepspeed.ai/tutorials/inference-tutorial/)를 참조하세요.
+
+## DP+PP [[dppp]]
+
+DeepSpeed [pipeline tutorial](https://www.deepspeed.ai/tutorials/pipeline/)에서 다음 다이어그램은 DP와 PP를 결합하는 방법을 보여줍니다.
+
+
+
+여기서 DP 랭크 0은 GPU2를 보지 못하고, DP 랭크 1은 GPU3을 보지 못하는 것이 중요합니다. DP에게는 딱 2개의 GPU인 것처럼 데이터를 공급합니다. GPU0은 PP를 사용하여 GPU2에게 일부 작업을 "비밀리에" 할당합니다. 그리고 GPU1도 GPU3을 도움으로 삼아 같은 방식으로 작업합니다.
+
+각 차원마다 적어도 2개의 GPU가 필요하므로 최소한 4개의 GPU가 필요합니다.
+
+구현:
+- [DeepSpeed](https://github.com/microsoft/DeepSpeed)
+- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM)
+- [Varuna](https://github.com/microsoft/varuna)
+- [SageMaker](https://arxiv.org/abs/2111.05972)
+- [OSLO](https://github.com/tunib-ai/oslo)
+
+🤗 Transformers 현황: 아직 구현되지 않음
+
+## DP+PP+TP [[dppptp]]
+
+더 효율적인 훈련을 위해 PP와 TP 및 DP를 결합하여 3D 병렬 처리를 사용합니다. 다음 다이어그램에서 이를 확인할 수 있습니다.
+
+
+
+이 다이어그램은 [3D parallelism: Scaling to trillion-parameter models](https://www.microsoft.com/en-us/research/blog/deepspeed-extreme-scale-model-training-for-everyone/)이라는 블로그 글에서 확인할 수 있습니다.
+
+각 차원마다 적어도 2개의 GPU가 필요하므로 최소한 8개의 GPU가 필요합니다.
+
+구현:
+- [DeepSpeed](https://github.com/microsoft/DeepSpeed) - DeepSpeed는 더욱 효율적인 DP인 ZeRO-DP라고도 부릅니다.
+- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM)
+- [Varuna](https://github.com/microsoft/varuna)
+- [SageMaker](https://arxiv.org/abs/2111.05972)
+- [OSLO](https://github.com/tunib-ai/oslo)
+
+🤗 Transformers 현황: 아직 구현되지 않음. PP와 TP가 없기 때문입니다.
+
+## ZeRO DP+PP+TP [[zero-dppptp]]
+
+DeepSpeed의 주요 기능 중 하나는 DP의 확장인 ZeRO입니다. ZeRO-DP에 대해 이미 [ZeRO Data Parallelism](#zero-data-parallelism)에서 논의되었습니다. 일반적으로 이는 PP나 TP를 필요로하지 않는 독립적인 기능입니다. 그러나 PP와 TP와 결합할 수도 있습니다.
+
+ZeRO-DP가 PP와 (선택적으로 TP와) 결합되면 일반적으로 ZeRO 단계 1(옵티마이저 분할)만 활성화됩니다.
+
+이론적으로는 ZeRO 단계 2(그라디언트 분할)를 파이프라인 병렬 처리와 함께 사용할 수도 있지만, 이는 성능에 나쁜 영향을 미칠 것입니다. 각 마이크로 배치마다 그라디언트를 샤딩하기 전에 추가적인 리듀스-스캐터 컬렉티브가 필요하며, 이는 잠재적으로 상당한 통신 오버헤드를 추가합니다. 파이프라인 병렬 처리의 특성상 작은 마이크로 배치가 사용되며, 산술 연산 강도(마이크로 배치 크기)를 균형 있게 유지하면서 파이프라인 버블(마이크로 배치 수)을 최소화하는 것에 중점을 둡니다. 따라서 해당 통신 비용은 문제가 될 것입니다.
+
+또한, PP로 인해 정상보다 적은 수의 레이어가 있으므로 메모리 절약은 크지 않을 것입니다. PP는 이미 그래디언트 크기를 ``1/PP``로 줄이기 때문에 그래디언트 샤딩의 절약 효과는 순수 DP보다는 미미합니다.
+
+ZeRO 단계 3도 같은 이유로 좋은 선택이 아닙니다 - 더 많은 노드 간 통신이 필요합니다.
+
+그리고 ZeRO가 있기 때문에 다른 이점은 ZeRO-Offload입니다. 이는 단계 1이므로 옵티마이저 상태를 CPU로 오프로드할 수 있습니다.
+
+구현:
+- [Megatron-DeepSpeed](https://github.com/microsoft/Megatron-DeepSpeed) 및 [BigScience의 Megatron-Deepspeed](https://github.com/bigscience-workshop/Megatron-DeepSpeed), 이전 저장소의 포크입니다.
+- [OSLO](https://github.com/tunib-ai/oslo)
+
+중요한 논문:
+
+- [Using DeepSpeed and Megatron to Train Megatron-Turing NLG 530B, A Large-Scale Generative Language Model](
+https://arxiv.org/abs/2201.11990)
+
+🤗 Transformers 현황: 아직 구현되지 않음, PP와 TP가 없기 때문입니다.
+
+## FlexFlow [[flexflow]]
+
+[FlexFlow](https://github.com/flexflow/FlexFlow)는 약간 다른 방식으로 병렬화 문제를 해결합니다.
+
+논문: ["Beyond Data and Model Parallelism for Deep Neural Networks" by Zhihao Jia, Matei Zaharia, Alex Aiken](https://arxiv.org/abs/1807.05358)
+
+이는 Sample-Operator-Attribute-Parameter를 기반으로 하는 일종의 4D 병렬화를 수행합니다.
+
+1. Sample = 데이터 병렬화 (샘플별 병렬)
+2. Operator = 단일 연산을 여러 하위 연산으로 병렬화
+3. Attribute = 데이터 병렬화 (길이별 병렬)
+4. Parameter = 모델 병렬화 (수평 또는 수직과 관계없이)
+
+예시:
+* Sample
+
+512 길이의 10개의 배치를 가정해 봅시다. 이를 sample 차원으로 2개의 장치에 병렬화하면, 10 x 512는 5 x 2 x 512가 됩니다.
+
+* Operator
+
+레이어 정규화를 수행한다면, 우선 std를 계산하고 두 번째로 mean을 계산한 다음 데이터를 정규화할 수 있습니다. Operator 병렬화는 std와 mean을 병렬로 계산할 수 있도록 합니다. 따라서 operator 차원으로 2개의 장치 (cuda:0, cuda:1)에 병렬화하면, 먼저 입력 데이터를 두 장치로 복사한 다음 cuda:0에서 std를 계산하고 cuda:1에서 동시에 mean을 계산합니다.
+
+* Attribute
+
+512 길이의 10개의 배치가 있습니다. 이를 attribute 차원으로 2개의 장치에 병렬화하면, 10 x 512는 10 x 2 x 256이 됩니다.
+
+* Parameter
+
+이는 tensor 모델 병렬화 또는 naive layer-wise 모델 병렬화와 유사합니다.
+
+
+
+이 프레임워크의 중요한 점은 (1) GPU/TPU/CPU 대 (2) RAM/DRAM 대 (3) 빠른 인트라-커넥트 대 느린 인터-커넥트와 같은 리소스를 고려하여 어디에서 어떤 병렬화를 사용할지를 알고리즘적으로 자동으로 최적화한다는 것입니다.
+
+하나 매우 중요한 측면은 FlexFlow가 정적이고 고정된 워크로드를 가진 모델에 대한 DNN 병렬화를 최적화하기 위해 설계되었다는 것입니다. 동적인 동작을 가진 모델은 반복마다 다른 병렬화 전략을 선호할 수 있습니다.
+
+따라서 이 프레임워크의 장점은 선택한 클러스터에서 30분 동안 시뮬레이션을 실행하고 이 특정 환경을 최적으로 활용하기 위한 최상의 전략을 제안한다는 것입니다. 부품을 추가/제거/교체하면 실행하고 그에 대한 계획을 다시 최적화한 후 훈련할 수 있습니다. 다른 설정은 자체적인 사용자 정의 최적화를 가질 수 있습니다.
+
+🤗 Transformers 현황: 아직 통합되지 않음. 이미 [transformers.utils.fx](https://github.com/huggingface/transformers/blob/master/src/transformers/utils/fx.py)를 통해 모델을 FX-추적할 수 있으며, 이는 FlexFlow의 선행 조건입니다. 따라서 어떤 작업을 수행해야 FlexFlow가 우리의 모델과 함께 작동할 수 있는지 파악해야 합니다.
+
+
+## 어떤 전략을 사용해야 할까요? [[which-strategy-to-use-when]]
+
+다음은 어떤 병렬화 전략을 언제 사용해야 하는지에 대한 매우 대략적인 개요입니다. 각 목록의 첫 번째 전략이 일반적으로 더 빠릅니다.
+
+**⇨ 단일 GPU**
+
+* 모델이 단일 GPU에 맞는 경우:
+
+ 1. 일반적인 사용
+
+* 모델이 단일 GPU에 맞지 않는 경우:
+
+ 1. ZeRO + CPU 및 옵션으로 NVMe 언로드
+ 2. 위와 동일하게 사용하되, 가장 큰 레이어가 단일 GPU에 맞지 않는 경우 Memory Centric Tiling(자세한 내용은 아래 참조)을 추가적으로 사용
+
+* 가장 큰 레이어가 단일 GPU에 맞지 않는 경우:
+
+1. ZeRO - [Memory Centric Tiling](https://deepspeed.readthedocs.io/en/latest/zero3.html#memory-centric-tiling) (MCT) 활성화. 이를 통해 크기가 매우 큰 레이어를 임의로 분할하여 순차적으로 실행할 수 있습니다. MCT는 GPU에 활성화된 매개변수의 수를 줄이지만 활성화 메모리에는 영향을 주지 않습니다. 현재 작성 기준으로 이 요구사항은 매우 드물기 때문에 사용자가 `torch.nn.Linear`를 수동으로 수정해야 합니다.
+
+**⇨ 단일 노드 / 다중 GPU**
+
+* 모델이 단일 GPU에 맞는 경우:
+
+ 1. DDP - 분산 DP
+ 2. ZeRO - 상황과 구성에 따라 빠를 수도 있고 그렇지 않을 수도 있습니다.
+
+* 모델이 단일 GPU에 맞지 않는 경우:
+
+ 1. PP
+ 2. ZeRO
+ 3. TP
+
+ NVLINK 또는 NVSwitch를 통한 매우 빠른 인트라-노드 연결이 있는 경우 이 세 가지 방법은 거의 동등할 것이며, 이러한 연결이 없는 경우 PP가 TP나 ZeRO보다 빠를 것입니다. 또한 TP의 차수도 영향을 줄 수 있습니다. 특정 설정에서 우승자를 찾기 위해 실험하는 것이 가장 좋습니다.
+
+ TP는 거의 항상 단일 노드 내에서 사용됩니다. 즉, TP 크기 <= 노드당 GPU 수입니다.
+
+* 가장 큰 레이어가 단일 GPU에 맞지 않는 경우:
+
+ 1. ZeRO를 사용하지 않을 경우 - PP만 사용할 수 없으므로 TP를 사용해야 합니다.
+ 2. ZeRO를 사용할 경우, "단일 GPU"의 항목과 동일한 항목 참조
+
+
+**⇨ 다중 노드 / 다중 GPU**
+
+* 빠른 노드 간 연결이 있는 경우:
+
+ 1. ZeRO - 모델에 대한 수정이 거의 필요하지 않습니다.
+ 2. PP+TP+DP - 통신이 적지만 모델에 대한 대규모 변경이 필요합니다.
+
+* 느린 노드 간 연결 및 GPU 메모리 부족한 경우:
+
+ 1. DP+PP+TP+ZeRO-1
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_train_special.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_train_special.md
new file mode 100644
index 0000000000000000000000000000000000000000..188db542f7c01f00396e64184e376bfea13744ec
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_train_special.md
@@ -0,0 +1,63 @@
+
+
+# Apple 실리콘에서 Pytorch 학습 [[PyTorch training on Apple silicon]]
+
+이전에는 Mac에서 모델을 학습할 때 CPU만 사용할 수 있었습니다. 그러나 이제 PyTorch v1.12의 출시로 Apple의 실리콘 GPU를 사용하여 훨씬 더 빠른 성능으로 모델을 학습할 수 있게 되었습니다. 이는 Pytorch에서 Apple의 Metal Performance Shaders (MPS)를 백엔드로 통합하면서 가능해졌습니다. [MPS 백엔드](https://pytorch.org/docs/stable/notes/mps.html)는 Pytorch 연산을 Metal 세이더로 구현하고 이 모듈들을 mps 장치에서 실행할 수 있도록 지원합니다.
+
+
+
+일부 Pytorch 연산들은 아직 MPS에서 지원되지 않아 오류가 발생할 수 있습니다. 이를 방지하려면 환경 변수 `PYTORCH_ENABLE_MPS_FALLBACK=1` 를 설정하여 CPU 커널을 대신 사용하도록 해야 합니다(이때 `UserWarning`이 여전히 표시될 수 있습니다).
+
+
+
+`mps` 장치를 이용하면 다음과 같은 이점들을 얻을 수 있습니다:
+
+* 로컬에서 더 큰 네트워크나 배치 크기로 학습 가능
+* GPU의 통합 메모리 아키텍처로 인해 메모리에 직접 접근할 수 있어 데이터 로딩 지연 감소
+* 클라우드 기반 GPU나 추가 GPU가 필요 없으므로 비용 절감 가능
+
+Pytorch가 설치되어 있는지 확인하고 시작하세요. MPS 가속은 macOS 12.3 이상에서 지원됩니다.
+
+```bash
+pip install torch torchvision torchaudio
+```
+
+[`TrainingArguments`]는 `mps` 장치가 사용 가능한 경우 이를 기본적으로 사용하므로 장치를 따로 설정할 필요가 없습니다. 예를 들어, MPS 백엔드를 자동으로 활성화하여 [run_glue.py](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-classification/run_glue.py) 스크립트를 아무 수정 없이 실행할 수 있습니다.
+
+```diff
+export TASK_NAME=mrpc
+
+python examples/pytorch/text-classification/run_glue.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --task_name $TASK_NAME \
+- --use_mps_device \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 32 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/ \
+ --overwrite_output_dir
+```
+
+`gloco`와 `nccl`과 같은 [분산 학습 백엔드](https://pytorch.org/docs/stable/distributed.html#backends)는 `mps` 장치에서 지원되지 않으므로, MPS 백엔드에서는 단일 GPU로만 학습이 가능합니다.
+
+Mac에서 가속된 PyTorch 학습에 대한 더 자세한 내용은 [Introducing Accelerated PyTorch Training on Mac](https://pytorch.org/blog/introducing-accelerated-pytorch-training-on-mac/) 블로그 게시물에서 확인할 수 있습니다.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_train_tpu_tf.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_train_tpu_tf.md
new file mode 100644
index 0000000000000000000000000000000000000000..28d4fdafb96ca85278c3190c7c46be29397ac2f8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perf_train_tpu_tf.md
@@ -0,0 +1,162 @@
+
+
+# TensorFlow로 TPU에서 훈련하기[[training-on-tpu-with-tensorflow]]
+
+
+
+자세한 설명이 필요하지 않고 바로 TPU 샘플 코드를 시작하고 싶다면 [우리의 TPU 예제 노트북!](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb)을 확인하세요.
+
+
+
+### TPU가 무엇인가요?[[what-is-a-tpu]]
+
+TPU는 **텐서 처리 장치**입니다. Google에서 설계한 하드웨어로, GPU처럼 신경망 내에서 텐서 연산을 더욱 빠르게 처리하기 위해 사용됩니다. 네트워크 훈련과 추론 모두에 사용할 수 있습니다. 일반적으로 Google의 클라우드 서비스를 통해 이용할 수 있지만, Google Colab과 Kaggle Kernel을 통해 소규모 TPU를 무료로 직접 이용할 수도 있습니다.
+
+[🤗 Transformers의 모든 Tensorflow 모델은 Keras 모델](https://huggingface.co/blog/tensorflow-philosophy)이기 때문에, 이 문서에서 다루는 대부분의 메소드는 대체로 모든 Keras 모델을 위한 TPU 훈련에 적용할 수 있습니다! 하지만 Transformer와 데이터 세트의 HuggingFace 생태계(hug-o-system?)에 특화된 몇 가지 사항이 있으며, 해당 사항에 대해 설명할 때 반드시 언급하도록 하겠습니다.
+
+### 어떤 종류의 TPU가 있나요?[[what-kinds-of-tpu-are-available]]
+
+신규 사용자는 TPU의 범위와 다양한 이용 방법에 대해 매우 혼란스러워하는 경우가 많습니다. **TPU 노드**와 **TPU VM**의 차이점은 가장 먼저 이해해야 할 핵심적인 구분 사항입니다.
+
+**TPU 노드**를 사용한다면, 실제로는 원격 TPU를 간접적으로 이용하는 것입니다. 네트워크와 데이터 파이프라인을 초기화한 다음, 이를 원격 노드로 전달할 별도의 VM이 필요합니다. Google Colab에서 TPU를 사용하는 경우, **TPU 노드** 방식으로 이용하게 됩니다.
+
+TPU 노드를 사용하는 것은 이를 사용하지 않는 사용자에게 예기치 않은 현상이 발생하기도 합니다! 특히, TPU는 파이썬 코드를 실행하는 기기(machine)와 물리적으로 다른 시스템에 있기 때문에 로컬 기기에 데이터를 저장할 수 없습니다. 즉, 컴퓨터의 내부 저장소에서 가져오는 데이터 파이프라인은 절대 작동하지 않습니다! 로컬 기기에 데이터를 저장하는 대신에, 데이터 파이프라인이 원격 TPU 노드에서 실행 중일 때에도 데이터 파이프라인이 계속 이용할 수 있는 Google Cloud Storage에 데이터를 저장해야 합니다.
+
+
+
+메모리에 있는 모든 데이터를 `np.ndarray` 또는 `tf.Tensor`로 맞출 수 있다면, Google Cloud Storage에 업로드할 필요 없이, Colab 또는 TPU 노드를 사용해서 해당 데이터에 `fit()` 할 수 있습니다.
+
+
+
+
+
+**🤗특수한 Hugging Face 팁🤗:** TF 코드 예제에서 볼 수 있는 `Dataset.to_tf_dataset()` 메소드와 그 상위 래퍼(wrapper)인 `model.prepare_tf_dataset()`는 모두 TPU 노드에서 작동하지 않습니다. 그 이유는 `tf.data.Dataset`을 생성하더라도 “순수한” `tf.data` 파이프라인이 아니며 `tf.numpy_function` 또는 `Dataset.from_generator()`를 사용하여 기본 HuggingFace `Dataset`에서 데이터를 전송하기 때문입니다. 이 HuggingFace `Dataset`는 로컬 디스크에 있는 데이터로 지원되며 원격 TPU 노드가 읽을 수 없습니다.
+
+
+
+TPU를 이용하는 두 번째 방법은 **TPU VM**을 사용하는 것입니다. TPU VM을 사용할 때, GPU VM에서 훈련하는 것과 같이 TPU가 장착된 기기에 직접 연결합니다. 특히 데이터 파이프라인과 관련하여, TPU VM은 대체로 작업하기 더 쉽습니다. 위의 모든 경고는 TPU VM에는 해당되지 않습니다!
+
+이 문서는 의견이 포함된 문서이며, 저희의 의견이 여기에 있습니다: **가능하면 TPU 노드를 사용하지 마세요.** TPU 노드는 TPU VM보다 더 복잡하고 디버깅하기가 더 어렵습니다. 또한 향후에는 지원되지 않을 가능성이 높습니다. Google의 최신 TPU인 TPUv4는 TPU VM으로만 이용할 수 있으므로, TPU 노드는 점점 더 "구식" 이용 방법이 될 것으로 전망됩니다. 그러나 TPU 노드를 사용하는 Colab과 Kaggle Kernel에서만 무료 TPU 이용이 가능한 것으로 확인되어, 필요한 경우 이를 다루는 방법을 설명해 드리겠습니다! 이에 대한 자세한 설명이 담긴 코드 샘플은 [TPU 예제 노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb)에서 확인하시기 바랍니다.
+
+### 어떤 크기의 TPU를 사용할 수 있나요?[[what-sizes-of-tpu-are-available]]
+
+단일 TPU(v2-8/v3-8/v4-8)는 8개의 복제본(replicas)을 실행합니다. TPU는 수백 또는 수천 개의 복제본을 동시에 실행할 수 있는 **pod**로 존재합니다. 단일 TPU를 하나 이상 사용하지만 전체 Pod보다 적게 사용하는 경우(예를 들면, v3-32), TPU 구성을 **pod 슬라이스**라고 합니다.
+
+Colab을 통해 무료 TPU에 이용하는 경우, 기본적으로 단일 v2-8 TPU를 제공받습니다.
+
+### XLA에 대해 들어본 적이 있습니다. XLA란 무엇이고 TPU와 어떤 관련이 있나요?[[i-keep-hearing-about-this-xla-thing-whats-xla-and-how-does-it-relate-to-tpus]]
+
+XLA는 최적화 컴파일러로, TensorFlow와 JAX에서 모두 사용됩니다. JAX에서는 유일한 컴파일러이지만, TensorFlow에서는 선택 사항입니다(하지만 TPU에서는 필수입니다!). Keras 모델을 훈련할 때 이를 활성화하는 가장 쉬운 방법은 `jit_compile=True` 인수를 `model.compile()`에 전달하는 것입니다. 오류가 없고 성능이 양호하다면, TPU로 전환할 준비가 되었다는 좋은 신호입니다!
+
+TPU에서 디버깅하는 것은 대개 CPU/GPU보다 조금 더 어렵기 때문에, TPU에서 시도하기 전에 먼저 XLA로 CPU/GPU에서 코드를 실행하는 것을 권장합니다. 물론 오래 학습할 필요는 없습니다. 즉, 모델과 데이터 파이프라인이 예상대로 작동하는지 확인하기 위해 몇 단계만 거치면 됩니다.
+
+
+
+XLA로 컴파일된 코드는 대체로 더 빠릅니다. 따라서 TPU에서 실행할 계획이 없더라도, `jit_compile=True`를 추가하면 성능이 향상될 수 있습니다. 하지만 XLA 호환성에 대한 아래 주의 사항을 반드시 확인하세요!
+
+
+
+
+
+**뼈아픈 경험에서 얻은 팁:** `jit_compile=True`를 사용하면 속도를 높이고 CPU/GPU 코드가 XLA와 호환되는지 검증할 수 있는 좋은 방법이지만, 실제 TPU에서 훈련할 때 그대로 남겨두면 많은 문제를 초래할 수 있습니다. XLA 컴파일은 TPU에서 암시적으로 이뤄지므로, 실제 TPU에서 코드를 실행하기 전에 해당 줄을 제거하는 것을 잊지 마세요!
+
+
+
+### 제 XLA 모델과 호환하려면 어떻게 해야 하나요?[[how-do-i-make-my-model-xla-compatible]]
+
+대부분의 경우, 여러분의 코드는 이미 XLA와 호환될 것입니다! 그러나 표준 TensorFlow에서 작동하지만, XLA에서는 작동하지 않는 몇 가지 사항이 있습니다. 이를 아래 세 가지 핵심 규칙으로 간추렸습니다:
+
+
+
+**특수한 HuggingFace 팁🤗:** 저희는 TensorFlow 모델과 손실 함수를 XLA와 호환되도록 재작성하는 데 많은 노력을 기울였습니다. 저희의 모델과 손실 함수는 대개 기본적으로 규칙 #1과 #2를 따르므로 `transformers` 모델을 사용하는 경우, 이를 건너뛸 수 있습니다. 하지만 자체 모델과 손실 함수를 작성할 때는 이러한 규칙을 잊지 마세요!
+
+
+
+#### XLA 규칙 #1: 코드에서 “데이터 종속 조건문”을 사용할 수 없습니다[[xla-rule-1-your-code-cannot-have-datadependent-conditionals]]
+
+어떤 `if`문도 `tf.Tensor` 내부의 값에 종속될 수 없다는 것을 의미합니다. 예를 들어, 이 코드 블록은 XLA로 컴파일할 수 없습니다!
+
+```python
+if tf.reduce_sum(tensor) > 10:
+ tensor = tensor / 2.0
+```
+
+처음에는 매우 제한적으로 보일 수 있지만, 대부분의 신경망 코드에서는 이를 수행할 필요가 없습니다. `tf.cond`를 사용하거나([여기](https://www.tensorflow.org/api_docs/python/tf/cond) 문서를 참조), 다음과 같이 조건문을 제거하고 대신 지표 변수를 사용하는 영리한 수학 트릭을 찾아내어 이 제한을 우회할 수 있습니다:
+
+```python
+sum_over_10 = tf.cast(tf.reduce_sum(tensor) > 10, tf.float32)
+tensor = tensor / (1.0 + sum_over_10)
+```
+
+이 코드는 위의 코드와 정확히 동일한 효과를 구현하지만, 조건문을 제거하여 문제 없이 XLA로 컴파일되도록 합니다!
+
+#### XLA 규칙 #2: 코드에서 "데이터 종속 크기"를 가질 수 없습니다[[xla-rule-2-your-code-cannot-have-datadependent-shapes]]
+
+코드에서 모든 `tf.Tensor` 객체의 크기가 해당 값에 종속될 수 없다는 것을 의미합니다. 예를 들어, `tf.unique` 함수는 입력에서 각 고유 값의 인스턴스 하나를 포함하는 `tensor`를 반환하기 때문에 XLA로 컴파일할 수 없습니다. 이 출력의 크기는 입력 `Tensor`가 얼마나 반복적인지에 따라 분명히 달라질 것이므로, XLA는 이를 처리하지 못합니다!
+
+일반적으로, 대부분의 신경망 코드는 기본값으로 규칙 2를 따릅니다. 그러나 문제가 되는 몇 가지 대표적인 사례가 있습니다. 가장 흔한 사례 중 하나는 **레이블 마스킹**을 사용하여 손실(loss)을 계산할 때, 해당 위치를 무시하도록 나타내기 위해 레이블을 음수 값으로 설정하는 경우입니다. 레이블 마스킹을 지원하는 NumPy나 PyTorch 손실 함수를 보면 [불 인덱싱](https://numpy.org/doc/stable/user/basics.indexing.html#boolean-array-indexing)을 사용하는 다음과 같은 코드를 자주 접할 수 있습니다:
+
+```python
+label_mask = labels >= 0
+masked_outputs = outputs[label_mask]
+masked_labels = labels[label_mask]
+loss = compute_loss(masked_outputs, masked_labels)
+mean_loss = torch.mean(loss)
+```
+
+이 코드는 NumPy나 PyTorch에서는 문제 없이 작동하지만, XLA에서는 손상됩니다! 왜 그럴까요? 얼마나 많은 위치가 마스킹되는지에 따라 `masked_outputs`와 `masked_labels`의 크기가 달라져서, **데이터 종속 크기**가 되기 때문입니다. 그러나 규칙 #1과 마찬가지로, 이 코드를 다시 작성하면 데이터 종속적 모양 크기가 정확히 동일한 출력을 산출할 수 있습니다.
+
+```python
+label_mask = tf.cast(labels >= 0, tf.float32)
+loss = compute_loss(outputs, labels)
+loss = loss * label_mask # Set negative label positions to 0
+mean_loss = tf.reduce_sum(loss) / tf.reduce_sum(label_mask)
+```
+
+여기서, 모든 위치에 대한 손실을 계산하지만, 평균을 계산할 때 분자와 분모 모두에서 마스크된 위치를 0으로 처리합니다. 이는 데이터 종속 크기를 방지하고 XLA 호환성을 유지하면서 첫 번째 블록과 정확히 동일한 결과를 산출합니다. 규칙 #1에서와 동일한 트릭을 사용하여 `tf.bool`을 `tf.float32`로 변환하고 이를 지표 변수로 사용합니다. 해당 트릭은 매우 유용하며, 자체 코드를 XLA로 변환해야 할 경우 기억해 두세요!
+
+#### XLA 규칙 #3: XLA는 각기 다른 입력 크기가 나타날 때마다 모델을 다시 컴파일해야 합니다[[xla-rule-3-xla-will-need-to-recompile-your-model-for-every-different-input-shape-it-sees]]
+
+이것은 가장 큰 문제입니다. 입력 크기가 매우 가변적인 경우, XLA는 모델을 반복해서 다시 컴파일해야 하므로 성능에 큰 문제가 발생할 수 있습니다. 이 문제는 토큰화 후 입력 텍스트의 길이가 가변적인 NLP 모델에서 주로 발생합니다. 다른 모달리티에서는 정적 크기가 더 흔하며, 해당 규칙이 훨씬 덜 문제시 됩니다.
+
+규칙 #3을 어떻게 우회할 수 있을까요? 핵심은 **패딩**입니다. 모든 입력을 동일한 길이로 패딩한 다음, `attention_mask`를 사용하면 어떤 XLA 문제도 없이 가변 크기에서 가져온 것과 동일한 결과를 가져올 수 있습니다. 그러나 과도한 패딩은 심각한 속도 저하를 야기할 수도 있습니다. 모든 샘플을 전체 데이터 세트의 최대 길이로 패딩하면, 무한한 패딩 토큰으로 구성된 배치가 생성되어 많은 연산과 메모리가 낭비될 수 있습니다!
+
+이 문제에 대한 완벽한 해결책은 없습니다. 하지만, 몇 가지 트릭을 시도해볼 수 있습니다. 한 가지 유용한 트릭은 **샘플 배치를 32 또는 64 토큰과 같은 숫자의 배수까지 패딩하는 것입니다.** 이는 토큰 수가 소폭 증가하지만, 모든 입력 크기가 32 또는 64의 배수여야 하기 때문에 고유한 입력 크기의 수가 대폭 줄어듭니다. 고유한 입력 크기가 적다는 것은 XLA 컴파일 횟수가 적어진다는 것을 의미합니다!
+
+
+
+**🤗특수한 HuggingFace 팁🤗:** 토크나이저와 데이터 콜레이터에 도움이 될 수 있는 메소드가 있습니다. 토크나이저를 불러올 때 `padding="max_length"` 또는 `padding="longest"`를 사용하여 패딩된 데이터를 출력하도록 할 수 있습니다. 토크나이저와 데이터 콜레이터는 나타나는 고유한 입력 크기의 수를 줄이기 위해 사용할 수 있는 `pad_to_multiple_of` 인수도 있습니다!
+
+
+
+### 실제 TPU로 모델을 훈련하려면 어떻게 해야 하나요?[[how-do-i-actually-train-my-model-on-tpu]]
+
+훈련이 XLA와 호환되고 (TPU 노드/Colab을 사용하는 경우) 데이터 세트가 적절하게 준비되었다면, TPU에서 실행하는 것은 놀랍도록 쉽습니다! 코드에서 몇 줄만 추가하여, TPU를 초기화하고 모델과 데이터 세트가 `TPUStrategy` 범위 내에 생성되도록 변경하면 됩니다. [우리의 TPU 예제 노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb)을 참조하여 실제로 작동하는 모습을 확인해 보세요!
+
+### 요약[[summary]]
+
+여기에 많은 내용이 포함되어 있으므로, TPU 훈련을 위한 모델을 준비할 때 따를 수 있는 간략한 체크리스트로 요약해 보겠습니다:
+
+- 코드가 XLA의 세 가지 규칙을 따르는지 확인합니다.
+- CPU/GPU에서 `jit_compile=True`로 모델을 컴파일하고 XLA로 훈련할 수 있는지 확인합니다.
+- 데이터 세트를 메모리에 가져오거나 TPU 호환 데이터 세트를 가져오는 방식을 사용합니다([노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb) 참조)
+- 코드를 Colab(accelerator가 “TPU”로 설정됨) 또는 Google Cloud의 TPU VM으로 마이그레이션합니다.
+- TPU 초기화 코드를 추가합니다([노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb) 참조)
+- `TPUStrategy`를 생성하고 데이터 세트를 가져오는 것과 모델 생성이 `strategy.scope()` 내에 있는지 확인합니다([노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb) 참조)
+- TPU로 이동할 때 `jit_compile=True`를 다시 설정하는 것을 잊지 마세요!
+- 🙏🙏🙏🥺🥺🥺
+- model.fit()을 불러옵니다.
+- 여러분이 해냈습니다!
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/performance.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/performance.md
new file mode 100644
index 0000000000000000000000000000000000000000..226bd5f249af5da28d4af4c33251f3eb2d588721
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/performance.md
@@ -0,0 +1,96 @@
+
+
+# 성능 및 확장성 [[performance-and-scalability]]
+
+점점 더 큰 규모의 트랜스포머 모델을 훈련하고 프로덕션에 배포하는 데에는 다양한 어려움이 따릅니다. 훈련 중에는 모델이 사용 가능한 GPU 메모리보다 더 많은 메모리를 필요로 하거나 훈련 속도가 매우 느릴 수 있으며, 추론을 위해 배포할 때는 제품 환경에서 요구되는 처리량으로 인해 과부하가 발생할 수 있습니다. 이 문서는 이러한 문제를 극복하고 사용 사례에 가장 적합한 설정을 찾도록 도움을 주기 위해 설계되었습니다. 훈련과 추론으로 가이드를 분할했는데, 이는 각각 다른 문제와 해결 방법이 있기 때문입니다. 그리고 각 가이드에는 다양한 종류의 하드웨어 설정에 대한 별도의 가이드가 있습니다(예: 훈련을 위한 단일 GPU vs 다중 GPU 또는 추론을 위한 CPU vs GPU).
+
+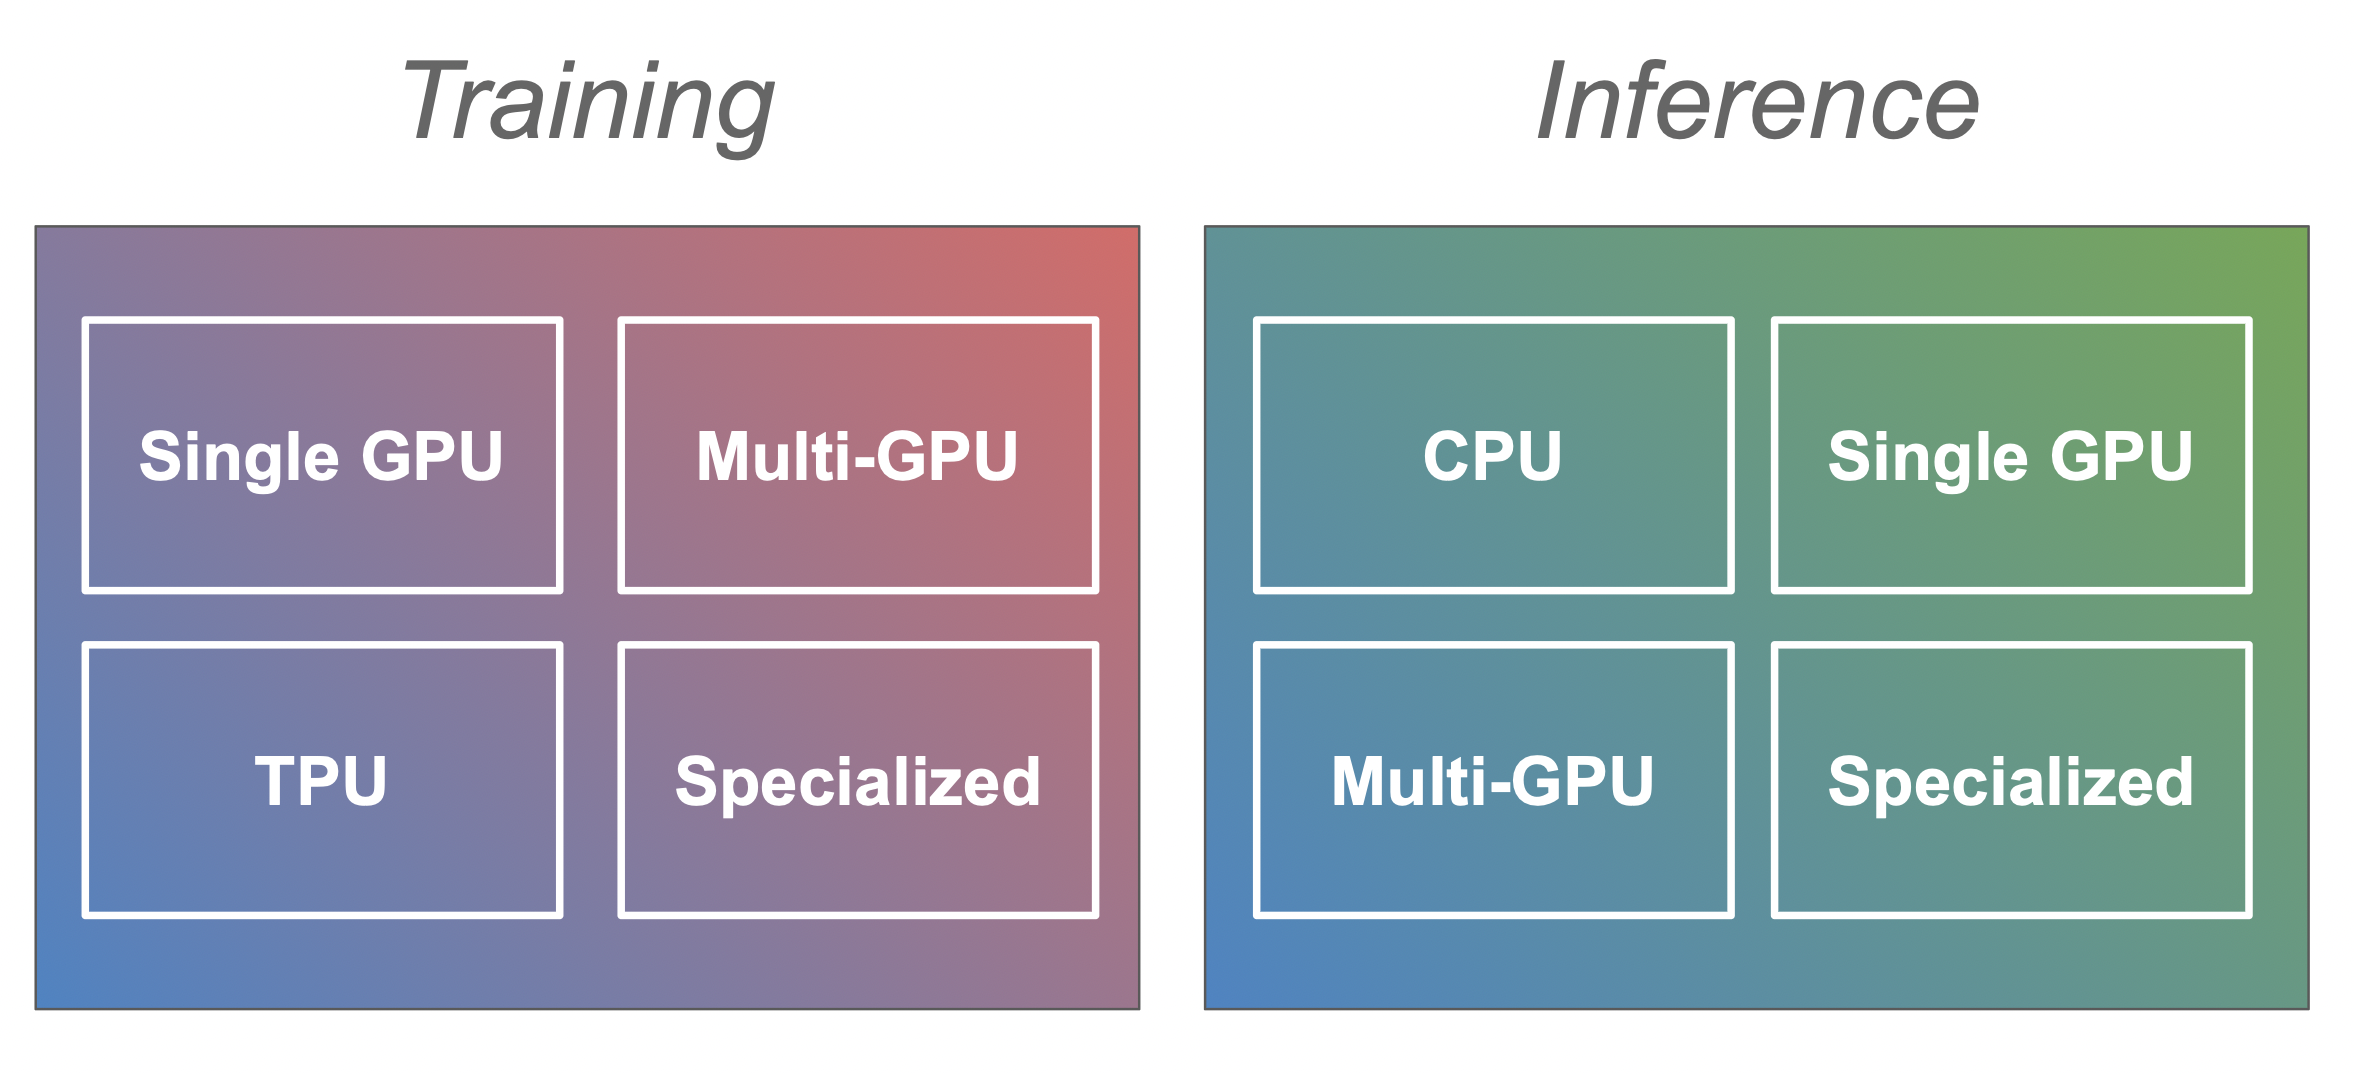
+
+이 문서는 사용자의 상황에 유용할 수 있는 방법들에 대한 개요 및 시작점 역할을 합니다.
+
+## 훈련 [[training]]
+
+효율적인 트랜스포머 모델 훈련에는 GPU나 TPU와 같은 가속기가 필요합니다. 가장 일반적인 경우는 단일 GPU만 사용하는 경우지만, 다중 GPU 및 CPU 훈련에 대한 섹션도 있습니다(곧 더 많은 내용이 추가될 예정).
+
+
+
+ 참고: 단일 GPU 섹션에서 소개된 대부분의 전략(예: 혼합 정밀도 훈련 또는 그라디언트 누적)은 일반적인 모델 훈련에도 적용되므로, 다중 GPU나 CPU 훈련과 같은 섹션을 살펴보기 전에 꼭 참고하시길 바랍니다.
+
+
+
+### 단일 GPU [[single-gpu]]
+
+단일 GPU에서 대규모 모델을 훈련하는 것은 어려울 수 있지만, 이를 가능하게 하는 여러 가지 도구와 방법이 있습니다. 이 섹션에서는 혼합 정밀도 훈련, 그라디언트 누적 및 체크포인팅, 효율적인 옵티마이저, 최적의 배치 크기를 결정하기 위한 전략 등에 대해 논의합니다.
+
+[단일 GPU 훈련 섹션으로 이동](perf_train_gpu_one)
+
+### 다중 GPU [[multigpu]]
+
+단일 GPU에서 훈련하는 것이 너무 느리거나 대규모 모델에 적합하지 않은 경우도 있습니다. 다중 GPU 설정으로 전환하는 것은 논리적인 단계이지만, 여러 GPU에서 한 번에 훈련하려면 각 GPU마다 모델의 전체 사본을 둘지, 혹은 모델 자체도 여러 GPU에 분산하여 둘지 등 새로운 결정을 내려야 합니다. 이 섹션에서는 데이터, 텐서 및 파이프라인 병렬화에 대해 살펴봅니다.
+
+[다중 GPU 훈련 섹션으로 이동](perf_train_gpu_many)
+
+### CPU [[cpu]]
+
+
+[CPU 훈련 섹션으로 이동](perf_train_cpu)
+
+
+### TPU [[tpu]]
+
+[_곧 제공될 예정_](perf_train_tpu)
+
+### 특수한 하드웨어 [[specialized-hardware]]
+
+[_곧 제공될 예정_](perf_train_special)
+
+## 추론 [[inference]]
+
+제품 및 서비스 환경에서 대규모 모델을 효율적으로 추론하는 것은 모델을 훈련하는 것만큼 어려울 수 있습니다. 이어지는 섹션에서는 CPU 및 단일/다중 GPU 설정에서 추론을 진행하는 단계를 살펴봅니다.
+
+### CPU [[cpu]]
+
+[CPU 추론 섹션으로 이동](perf_infer_cpu)
+
+### 단일 GPU [[single-gpu]]
+
+[단일 GPU 추론 섹션으로 이동](perf_infer_gpu_one)
+
+### 다중 GPU [[multigpu]]
+
+[다중 GPU 추론 섹션으로 이동](perf_infer_gpu_many)
+
+### 특수한 하드웨어 [[specialized-hardware]]
+
+[_곧 제공될 예정_](perf_infer_special)
+
+## 하드웨어 [[hardware]]
+
+하드웨어 섹션에서는 자신만의 딥러닝 장비를 구축할 때 유용한 팁과 요령을 살펴볼 수 있습니다.
+
+[하드웨어 섹션으로 이동](perf_hardware)
+
+
+## 기여하기 [[contribute]]
+
+이 문서는 완성되지 않은 상태이며, 추가해야 할 내용이나 수정 사항이 많이 있습니다. 따라서 추가하거나 수정할 내용이 있으면 주저하지 말고 PR을 열어 주시거나, 자세한 내용을 논의하기 위해 Issue를 시작해 주시기 바랍니다.
+
+A가 B보다 좋다고 하는 기여를 할 때는, 재현 가능한 벤치마크와/또는 해당 정보의 출처 링크를 포함해주세요(당신으로부터의 직접적인 정보가 아닌 경우).
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perplexity.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perplexity.md
new file mode 100644
index 0000000000000000000000000000000000000000..9de84a5f289b942875aa88386f430cc67e306bb9
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/perplexity.md
@@ -0,0 +1,135 @@
+
+
+# 고정 길이 모델의 펄플렉서티(Perplexity)[[perplexity-of-fixedlength-models]]
+
+[[open-in-colab]]
+
+펄플렉서티(Perplexity, PPL)는 가장 일반적인 언어 모델 평가지표 중 하나입니다.
+자세히 알아보기 전에 이 평가지표는 고전적인 언어 모델(자기회귀 또는 인과적 언어 모델이라고도 함)에만 적용되며 BERT와 같은 마스킹된 언어 모델에는 잘 적용하지 않습니다 (BERT는 [summary of the models](../en/model_summary) 문서를 참고하세요).
+
+펄플렉서티는 시퀀스의 음의 로그 우도(negative log-likelihood, NLL) 값의 평균에 지수(exponentiate)를 취한 값으로 정의됩니다.
+토큰화된 시퀀스 \\(X = (x_0, x_1, \dots, x_t)\\) 가 있을 때, \\(X\\) 의 펄플렉서티는 아래 수식과 같이 구할 수 있습니다.
+
+$$\text{PPL}(X) = \exp \left\{ {-\frac{1}{t}\sum_i^t \log p_\theta (x_i|x_{
+
+지원하는 모든 태스크와 쓸 수 있는 매개변수를 담은 목록은 [`pipeline`] 설명서를 참고해주세요.
+
+
+
+## Pipeline 사용하기[[pipeline-usage]]
+
+각 태스크마다 고유의 [`pipeline`]이 있지만, 개별 파이프라인을 담고있는 추상화된 [`pipeline`]를 사용하는 것이 일반적으로 더 간단합니다. [`pipeline`]은 태스크에 알맞게 추론이 가능한 기본 모델과 전처리 클래스를 자동으로 로드합니다.
+
+1. 먼저 [`pipeline`]을 생성하고 태스크를 지정하세요.
+
+```py
+>>> from transformers import pipeline
+
+>>> generator = pipeline(task="automatic-speech-recognition")
+```
+
+2. 그리고 [`pipeline`]에 입력을 넣어주세요.
+
+```py
+>>> generator("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': 'I HAVE A DREAM BUT ONE DAY THIS NATION WILL RISE UP LIVE UP THE TRUE MEANING OF ITS TREES'}
+```
+
+기대했던 결과가 아닌가요? Hub에서 [가장 많이 다운로드된 자동 음성 인식 모델](https://huggingface.co/models?pipeline_tag=automatic-speech-recognition&sort=downloads)로 더 나은 결과를 얻을 수 있는지 확인해보세요.
+다음은 [openai/whisper-large](https://huggingface.co/openai/whisper-large)로 시도해보겠습니다.
+
+```py
+>>> generator = pipeline(model="openai/whisper-large")
+>>> generator("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
+```
+
+훨씬 더 나아졌군요!
+Hub의 모델들은 여러 다양한 언어와 전문분야를 아우르기 때문에 꼭 자신의 언어나 분야에 특화된 모델을 찾아보시기 바랍니다.
+브라우저를 벗어날 필요없이 Hub에서 직접 모델의 출력을 확인하고 다른 모델과 비교해서 자신의 상황에 더 적합한지, 애매한 입력을 더 잘 처리하는지도 확인할 수 있습니다.
+만약 상황에 알맞는 모델을 없다면 언제나 직접 [훈련](training)시킬 수 있습니다!
+
+입력이 여러 개 있는 경우, 리스트 형태로 전달할 수 있습니다.
+
+```py
+generator(
+ [
+ "https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac",
+ "https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/1.flac",
+ ]
+)
+```
+
+전체 데이터세트을 순회하거나 웹서버에 올려두어 추론에 사용하고 싶다면, 각 상세 페이지를 참조하세요.
+
+[데이터세트에서 Pipeline 사용하기](#using-pipelines-on-a-dataset)
+
+[웹서버에서 Pipeline 사용하기](./pipeline_webserver)
+
+## 매개변수[[parameters]]
+
+[`pipeline`]은 많은 매개변수를 지원합니다. 특정 태스크용인 것도 있고, 범용인 것도 있습니다.
+일반적으로 원하는 위치에 어디든 매개변수를 넣을 수 있습니다.
+
+```py
+generator(model="openai/whisper-large", my_parameter=1)
+out = generate(...) # This will use `my_parameter=1`.
+out = generate(..., my_parameter=2) # This will override and use `my_parameter=2`.
+out = generate(...) # This will go back to using `my_parameter=1`.
+```
+
+중요한 3가지 매개변수를 살펴보겠습니다.
+
+### 기기(device)[[device]]
+
+`device=n`처럼 기기를 지정하면 파이프라인이 자동으로 해당 기기에 모델을 배치합니다.
+파이토치에서나 텐서플로우에서도 모두 작동합니다.
+
+```py
+generator(model="openai/whisper-large", device=0)
+```
+
+모델이 GPU 하나에 돌아가기 버겁다면, `device_map="auto"`를 지정해서 🤗 [Accelerate](https://huggingface.co/docs/accelerate)가 모델 가중치를 어떻게 로드하고 저장할지 자동으로 결정하도록 할 수 있습니다.
+
+```py
+#!pip install accelerate
+generator(model="openai/whisper-large", device_map="auto")
+```
+
+### 배치 사이즈[[batch-size]]
+
+기본적으로 파이프라인은 [여기](https://huggingface.co/docs/transformers/main_classes/pipelines#pipeline-batching)에 나온 이유로 추론을 일괄 처리하지 않습니다. 간단히 설명하자면 일괄 처리가 반드시 더 빠르지 않고 오히려 더 느려질 수도 있기 때문입니다.
+
+하지만 자신의 상황에 적합하다면, 이렇게 사용하세요.
+
+```py
+generator(model="openai/whisper-large", device=0, batch_size=2)
+audio_filenames = [f"audio_{i}.flac" for i in range(10)]
+texts = generator(audio_filenames)
+```
+
+파이프라인 위 제공된 10개의 오디오 파일을 추가로 처리하는 코드 없이 (일괄 처리에 보다 효과적인 GPU 위) 모델에 2개씩 전달합니다.
+출력은 일괄 처리하지 않았을 때와 똑같아야 합니다. 파이프라인에서 속도를 더 낼 수도 있는 방법 중 하나일 뿐입니다.
+
+파이프라인은 일괄 처리의 복잡한 부분을 줄여주기도 합니다. (예를 들어 긴 오디오 파일처럼) 여러 부분으로 나눠야 모델이 처리할 수 있는 것을 [*chunk batching*](./main_classes/pipelines#pipeline-chunk-batching)이라고 하는데, 파이프라인을 사용하면 자동으로 나눠줍니다.
+
+### 특정 태스크용 매개변수[[task-specific-parameters]]
+
+각 태스크마다 구현할 때 유연성과 옵션을 제공하기 위해 태스크용 매개변수가 있습니다.
+예를 들어 [`transformers.AutomaticSpeechRecognitionPipeline.__call__`] 메서드에는 동영상의 자막을 넣을 때 유용할 것 같은 `return_timestamps` 매개변수가 있습니다.
+
+```py
+>>> # Not using whisper, as it cannot provide timestamps.
+>>> generator = pipeline(model="facebook/wav2vec2-large-960h-lv60-self", return_timestamps="word")
+>>> generator("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': 'I HAVE A DREAM BUT ONE DAY THIS NATION WILL RISE UP AND LIVE OUT THE TRUE MEANING OF ITS CREED', 'chunks': [{'text': 'I', 'timestamp': (1.22, 1.24)}, {'text': 'HAVE', 'timestamp': (1.42, 1.58)}, {'text': 'A', 'timestamp': (1.66, 1.68)}, {'text': 'DREAM', 'timestamp': (1.76, 2.14)}, {'text': 'BUT', 'timestamp': (3.68, 3.8)}, {'text': 'ONE', 'timestamp': (3.94, 4.06)}, {'text': 'DAY', 'timestamp': (4.16, 4.3)}, {'text': 'THIS', 'timestamp': (6.36, 6.54)}, {'text': 'NATION', 'timestamp': (6.68, 7.1)}, {'text': 'WILL', 'timestamp': (7.32, 7.56)}, {'text': 'RISE', 'timestamp': (7.8, 8.26)}, {'text': 'UP', 'timestamp': (8.38, 8.48)}, {'text': 'AND', 'timestamp': (10.08, 10.18)}, {'text': 'LIVE', 'timestamp': (10.26, 10.48)}, {'text': 'OUT', 'timestamp': (10.58, 10.7)}, {'text': 'THE', 'timestamp': (10.82, 10.9)}, {'text': 'TRUE', 'timestamp': (10.98, 11.18)}, {'text': 'MEANING', 'timestamp': (11.26, 11.58)}, {'text': 'OF', 'timestamp': (11.66, 11.7)}, {'text': 'ITS', 'timestamp': (11.76, 11.88)}, {'text': 'CREED', 'timestamp': (12.0, 12.38)}]}
+```
+
+보시다시피 모델이 텍스트를 추론할 뿐만 아니라 각 단어를 말한 시점까지도 출력했습니다.
+
+태스크마다 다양한 매개변수를 가지고 있는데요. 원하는 태스크의 API를 참조해서 바꿔볼 수 있는 여러 매개변수를 살펴보세요!
+지금까지 다뤄본 [`~transformers.AutomaticSpeechRecognitionPipeline`]에는 `chunk_length_s` 매개변수가 있습니다. 영화나 1시간 분량의 동영상의 자막 작업을 할 때처럼, 일반적으로 모델이 자체적으로 처리할 수 없는 매우 긴 오디오 파일을 처리할 때 유용하죠.
+
+
+도움이 될 만한 매개변수를 찾지 못했다면 언제든지 [요청](https://github.com/huggingface/transformers/issues/new?assignees=&labels=feature&template=feature-request.yml)해주세요!
+
+
+## 데이터세트에서 Pipeline 사용하기[[using-pipelines-on-a-dataset]]
+
+파이프라인은 대규모 데이터세트에서도 추론 작업을 할 수 있습니다. 이때 이터레이터를 사용하는 걸 추천드립니다.
+
+```py
+def data():
+ for i in range(1000):
+ yield f"My example {i}"
+
+
+pipe = pipe(model="openai-community/gpt2", device=0)
+generated_characters = 0
+for out in pipe(data()):
+ generated_characters += len(out["generated_text"])
+```
+
+이터레이터 `data()`는 각 결과를 호출마다 생성하고, 파이프라인은 입력이 순회할 수 있는 자료구조임을 자동으로 인식하여 GPU에서 기존 데이터가 처리되는 동안 새로운 데이터를 가져오기 시작합니다.(이때 내부적으로 [DataLoader](https://pytorch.org/docs/stable/data.html#torch.utils.data.DataLoader)를 사용해요.) 이 과정은 전체 데이터세트를 메모리에 적재하지 않고도 GPU에 최대한 빠르게 새로운 작업을 공급할 수 있기 때문에 중요합니다.
+
+그리고 일괄 처리가 더 빠를 수 있기 때문에, `batch_size` 매개변수를 조정해봐도 좋아요.
+
+데이터세트를 순회하는 가장 간단한 방법은 🤗 [Datasets](https://github.com/huggingface/datasets/)를 활용하는 것인데요.
+
+```py
+# KeyDataset is a util that will just output the item we're interested in.
+from transformers.pipelines.pt_utils import KeyDataset
+
+pipe = pipeline(model="hf-internal-testing/tiny-random-wav2vec2", device=0)
+dataset = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation[:10]")
+
+for out in pipe(KeyDataset(dataset["audio"])):
+ print(out)
+```
+
+
+## 웹서버에서 Pipeline 사용하기[[using-pipelines-for-a-webserver]]
+
+
+추론 엔진을 만드는 과정은 따로 페이지를 작성할만한 복잡한 주제입니다.
+
+
+[Link](./pipeline_webserver)
+
+## 비전 Pipeline[[vision-pipeline]]
+
+비전 태스크를 위해 [`pipeline`]을 사용하는 일은 거의 동일합니다.
+
+태스크를 지정하고 이미지를 분류기에 전달하면 됩니다. 이미지는 인터넷 링크 또는 로컬 경로의 형태로 전달해주세요. 예를 들어 아래에 표시된 고양이는 어떤 종인가요?
+
+
+
+```py
+>>> from transformers import pipeline
+
+>>> vision_classifier = pipeline(model="google/vit-base-patch16-224")
+>>> preds = vision_classifier(
+... images="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.4335, 'label': 'lynx, catamount'}, {'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}, {'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}, {'score': 0.0239, 'label': 'Egyptian cat'}, {'score': 0.0229, 'label': 'tiger cat'}]
+```
+
+### 텍스트 Pipeline[[text-pipeline]]
+
+NLP 태스크를 위해 [`pipeline`]을 사용하는 일도 거의 동일합니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> # This model is a `zero-shot-classification` model.
+>>> # It will classify text, except you are free to choose any label you might imagine
+>>> classifier = pipeline(model="facebook/bart-large-mnli")
+>>> classifier(
+... "I have a problem with my iphone that needs to be resolved asap!!",
+... candidate_labels=["urgent", "not urgent", "phone", "tablet", "computer"],
+... )
+{'sequence': 'I have a problem with my iphone that needs to be resolved asap!!', 'labels': ['urgent', 'phone', 'computer', 'not urgent', 'tablet'], 'scores': [0.504, 0.479, 0.013, 0.003, 0.002]}
+```
+
+### 멀티모달 Pipeline[[multimodal-pipeline]]
+
+[`pipeline`]은 여러 모달리티(역주: 오디오, 비디오, 텍스트와 같은 데이터 형태)를 지원합니다. 예시로 시각적 질의응답(VQA; Visual Question Answering) 태스크는 텍스트와 이미지를 모두 사용합니다. 그 어떤 이미지 링크나 묻고 싶은 질문도 자유롭게 전달할 수 있습니다. 이미지는 URL 또는 로컬 경로의 형태로 전달해주세요.
+
+예를 들어 이 [거래명세서 사진](https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png)에서 거래명세서 번호를 묻고 싶다면,
+
+```py
+>>> from transformers import pipeline
+
+>>> vqa = pipeline(model="impira/layoutlm-document-qa")
+>>> vqa(
+... image="https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png",
+... question="What is the invoice number?",
+... )
+[{'score': 0.42514941096305847, 'answer': 'us-001', 'start': 16, 'end': 16}]
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/pipeline_webserver.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/pipeline_webserver.md
new file mode 100644
index 0000000000000000000000000000000000000000..b7d5366c57c4ef2edc7fb7505304299cf76317c2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/pipeline_webserver.md
@@ -0,0 +1,144 @@
+
+
+# 웹 서버를 위한 파이프라인 사용하기[[using_pipelines_for_a_webserver]]
+
+
+추론 엔진을 만드는 것은 복잡한 주제이며, "최선의" 솔루션은 문제 공간에 따라 달라질 가능성이 높습니다. CPU 또는 GPU를 사용하는지에 따라 다르고 낮은 지연 시간을 원하는지, 높은 처리량을 원하는지, 다양한 모델을 지원할 수 있길 원하는지, 하나의 특정 모델을 고도로 최적화하길 원하는지 등에 따라 달라집니다. 이 주제를 해결하는 방법에는 여러 가지가 있으므로, 이 장에서 제시하는 것은 처음 시도해 보기에 좋은 출발점일 수는 있지만, 이 장을 읽는 여러분이 필요로 하는 최적의 솔루션은 아닐 수 있습니다.
+
+
+핵심적으로 이해해야 할 점은 [dataset](pipeline_tutorial#using-pipelines-on-a-dataset)를 다룰 때와 마찬가지로 반복자를 사용 가능하다는 것입니다. 왜냐하면, 웹 서버는 기본적으로 요청을 기다리고 들어오는 대로 처리하는 시스템이기 때문입니다.
+
+보통 웹 서버는 다양한 요청을 동시에 다루기 위해 매우 다중화된 구조(멀티 스레딩, 비동기 등)를 지니고 있습니다. 반면에, 파이프라인(대부분 파이프라인 안에 있는 모델)은 병렬처리에 그다지 좋지 않습니다. 왜냐하면 파이프라인은 많은 RAM을 차지하기 때문입니다. 따라서, 파이프라인이 실행 중이거나 계산 집약적인 작업 중일 때 모든 사용 가능한 리소스를 제공하는 것이 가장 좋습니다.
+
+이 문제를 우리는 웹 서버가 요청을 받고 보내는 가벼운 부하를 처리하고, 실제 작업을 처리하는 단일 스레드를 갖는 방법으로 해결할 것입니다. 이 예제는 `starlette` 라이브러리를 사용합니다.
+실제 프레임워크는 중요하지 않지만, 다른 프레임워크를 사용하는 경우 동일한 효과를 보기 위해선 코드를 조정하거나 변경해야 할 수 있습니다.
+
+`server.py`를 생성하세요:
+
+```py
+from starlette.applications import Starlette
+from starlette.responses import JSONResponse
+from starlette.routing import Route
+from transformers import pipeline
+import asyncio
+
+
+async def homepage(request):
+ payload = await request.body()
+ string = payload.decode("utf-8")
+ response_q = asyncio.Queue()
+ await request.app.model_queue.put((string, response_q))
+ output = await response_q.get()
+ return JSONResponse(output)
+
+
+async def server_loop(q):
+ pipe = pipeline(model="google-bert/bert-base-uncased")
+ while True:
+ (string, response_q) = await q.get()
+ out = pipe(string)
+ await response_q.put(out)
+
+
+app = Starlette(
+ routes=[
+ Route("/", homepage, methods=["POST"]),
+ ],
+)
+
+
+@app.on_event("startup")
+async def startup_event():
+ q = asyncio.Queue()
+ app.model_queue = q
+ asyncio.create_task(server_loop(q))
+```
+
+이제 다음 명령어로 실행시킬 수 있습니다:
+
+```bash
+uvicorn server:app
+```
+
+이제 쿼리를 날려볼 수 있습니다:
+
+```bash
+curl -X POST -d "test [MASK]" http://localhost:8000/
+#[{"score":0.7742936015129089,"token":1012,"token_str":".","sequence":"test."},...]
+```
+
+자, 이제 웹 서버를 만드는 방법에 대한 좋은 개념을 알게 되었습니다!
+
+중요한 점은 모델을 **한 번만** 가져온다는 것입니다. 따라서 웹 서버에는 모델의 사본이 없습니다. 이런 방식은 불필요한 RAM이 사용되지 않습니다. 그런 다음 큐 메커니즘을 사용하면, 다음과 같은
+동적 배치를 사용하기 위해 추론 전 단계에 몇 개의 항목을 축적하는 것과 같은 멋진 작업을 할 수 있습니다:
+
+
+코드는 의도적으로 가독성을 위해 의사 코드처럼 작성되었습니다!
+아래 코드를 작동시키기 전에 시스템 자원이 충분한지 확인하세요!
+
+
+```py
+(string, rq) = await q.get()
+strings = []
+queues = []
+while True:
+ try:
+ (string, rq) = await asyncio.wait_for(q.get(), timeout=0.001) # 1ms
+ except asyncio.exceptions.TimeoutError:
+ break
+ strings.append(string)
+ queues.append(rq)
+strings
+outs = pipe(strings, batch_size=len(strings))
+for rq, out in zip(queues, outs):
+ await rq.put(out)
+```
+
+다시 말씀 드리자면, 제안된 코드는 가독성을 위해 최적화되었으며, 최상의 코드는 아닙니다.
+첫째, 배치 크기 제한이 없으며 이는 일반적으로 좋은 방식이 아닙니다.
+둘째, 모든 큐 가져오기에서 타임아웃이 재설정되므로 추론을 실행하기 전에 1ms보다 훨씬 오래 기다릴 수 있습니다(첫 번째 요청을 그만큼 지연시킴).
+
+단일 1ms 길이의 데드라인을 두는 편이 더 좋습니다.
+
+이 방식을 사용하면 큐가 비어 있어도 항상 1ms를 기다리게 될 것입니다.
+큐에 아무것도 없을 때 추론을 원하는 경우에는 최선의 방법이 아닐 수 있습니다.
+하지만 배치 작업이 사용례에 따라 정말로 중요하다면 의미가 있을 수도 있습니다.
+다시 말하지만, 최상의 솔루션은 없습니다.
+
+## 고려해야 할 몇 가지 사항[[few_things_you_might want_to_consider]]
+
+### 에러 확인[[error_checking]]
+
+프로덕션 환경에서는 문제가 발생할 여지가 많습니다.
+메모리가 모자라거나, 공간이 부족하거나, 모델을 가져오는 데에 실패하거나, 쿼리가 잘못되었거나, 쿼리는 정확해도 모델 설정이 잘못되어 실행에 실패하는 등등 많은 경우가 존재합니다.
+
+일반적으로 서버가 사용자에게 오류를 출력하는 것이 좋으므로
+오류를 표시하기 위해 `try...except` 문을 많이 추가하는 것이 좋습니다.
+하지만 보안 상황에 따라 모든 오류를 표시하는 것은 보안상 위험할 수도 있다는 점을 명심해야합니다.
+
+### 서킷 브레이킹[[circuit_breaking]]
+
+웹 서버는 일반적으로 서킷 브레이킹을 수행할 때 더 나은 상황에 직면합니다.
+즉, 이는 서버가 쿼리를 무기한 기다리는 대신 과부하 상태일 때 적절한 오류를 반환하는 것을 의미합니다.
+서버가 매우 오랜 시간 동안 대기하거나 적당한 시간이 지난 후에 504 에러를 반환하는 대신 503 에러를 빠르게 반환하게 하는 것입니다.
+
+제안된 코드에는 단일 큐가 있으므로 구현하기가 비교적 쉽습니다.
+큐 크기를 확인하는 것은 웹 서버가 과부하 상항 하에 있을 때 에러를 반환하기 위한 가장 기초적인 작업입니다.
+
+### 메인 쓰레드 차단[[blocking_the_main_thread]]
+
+현재 PyTorch는 비동기 처리를 지원하지 않으며, 실행 중에는 메인 스레드가 차단됩니다.
+따라서 PyTorch를 별도의 스레드/프로세스에서 실행하도록 강제하는 것이 좋습니다.
+여기서는 이 작업이 수행되지 않았습니다. 왜냐하면 코드가 훨씬 더 복잡하기 때문입니다(주로 스레드, 비동기 처리, 큐가 서로 잘 맞지 않기 때문입니다).
+하지만 궁극적으로는 같은 작업을 수행하는 것입니다.
+
+단일 항목의 추론이 오래 걸린다면 (> 1초), 메인 쓰레드를 차단하는 것은 중요할 수 있습니다. 왜냐하면 이 경우 추론 중 모든 쿼리는 오류를 받기 전에 1초를 기다려야 하기 때문입니다.
+
+### 동적 배치[[dynamic_batching]]
+
+일반적으로, 배치 처리가 1개 항목을 한 번에 전달하는 것에 비해 반드시 성능 향상이 있는 것은 아닙니다(자세한 내용은 [`batching details`](./main_classes/pipelines#pipeline-batching)을 참고하세요).
+하지만 올바른 설정에서 사용하면 매우 효과적일 수 있습니다.
+API에는 기본적으로 속도 저하의 가능성이 매우 높기 때문에 동적 배치 처리가 없습니다.
+하지만 매우 큰 모델인 BLOOM 추론의 경우 동적 배치 처리는 모든 사람에게 적절한 경험을 제공하는 데 **필수**입니다.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/pr_checks.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/pr_checks.md
new file mode 100644
index 0000000000000000000000000000000000000000..1d155cd1fb9ddbc0f4c70b16faeba261b75f573f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/pr_checks.md
@@ -0,0 +1,200 @@
+
+
+# Pull Request에 대한 검사 [[checks-on-a-pull-request]]
+
+🤗 Transformers에서 Pull Request를 열 때, 기존에 있는 것을 망가뜨리지 않는지 확인하기 위해 상당한 수의 검사가 실행됩니다. 이러한 검사는 다음과 같은 네 가지 유형으로 구성됩니다:
+- 일반적인 테스트
+- 문서 빌드
+- 코드 및 문서 스타일
+- 일반 저장소 일관성
+
+이 문서에서는 이러한 다양한 검사와 그 이유를 설명하고, PR에서 하나 이상의 검사가 실패한 경우 로컬에서 어떻게 디버그하는지 알아보겠습니다.
+
+참고로, 이러한 검사를 사용하려면 개발 설치가 필요합니다:
+
+```bash
+pip install transformers[dev]
+```
+
+또는 Transformers 저장소 내에 편집 가능한 설치가 필요합니다:
+
+```bash
+pip install -e .[dev]
+```
+
+Transformers의 선택적 종속성 수가 많이 늘어났기 때문에 개발 설치를 실패할 수도 있습니다. 개발 설치가 실패하는 경우, 작업 중인 Deep Learning 프레임워크 (PyTorch, TensorFlow 및/또는 Flax)를 설치하고 다음 명령을 실행하세요.
+
+```bash
+pip install transformers[quality]
+```
+
+편집 가능한 설치의 경우는 다음 명령을 실행하세요.
+
+```bash
+pip install -e .[quality]
+```
+
+
+## 테스트 [[tests]]
+
+`ci/circleci: run_tests_`로 시작하는 모든 작업은 Transformers 테스트 모음의 일부를 실행합니다. 이러한 작업은 특정 환경에서 일부 라이브러리에 중점을 둡니다. 예를 들어 `ci/circleci: run_tests_pipelines_tf`는 TensorFlow만 설치된 환경에서 파이프라인 테스트를 실행합니다.
+
+테스트 모듈에서 실제로 변경 사항이 없을 때 테스트를 실행하지 않기 위해, 테스트 모음의 일부만 실행됩니다. 라이브러리의 변경 전후에 대한 차이를 확인하기 위해 유틸리티가 실행되고, 해당 차이에 영향을 받는 테스트가 선택됩니다. 이 유틸리티는 로컬에서 다음과 같이 실행할 수 있습니다:
+
+```bash
+python utils/tests_fetcher.py
+```
+
+Transformers 저장소의 최상단에서 실행합니다. 이 유틸리티는 다음과 같은 작업을 수행합니다:
+
+1. 변경 사항이 있는 파일마다 변경 사항이 코드인지 주석 또는 문서 문자열인지 확인합니다. 실제 코드 변경이 있는 파일만 유지됩니다.
+2. 소스 코드 파일의 각 파일에 대해 재귀적으로 영향을 주는 모든 파일을 제공하는 내부 맵을 작성합니다. 모듈 B가 모듈 A를 가져오면 모듈 A는 모듈 B에 영향을 줍니다. 재귀적인 영향에는 각 모듈이 이전 모듈을 가져오는 모듈 체인이 필요합니다.
+3. 단계 1에서 수집한 파일에 이 맵을 적용하여 PR에 영향을 받는 모델 파일 목록을 얻습니다.
+4. 각 파일을 해당하는 테스트 파일에 매핑하고 실행할 테스트 목록을 가져옵니다.
+
+로컬에서 스크립트를 실행하면 단계 1, 3 및 4의 결과를 출력하여 실행되는 테스트를 알 수 있습니다. 스크립트는 또한 `test_list.txt`라는 파일을 생성하여 실행할 테스트 목록을 포함하며, 다음 명령으로 해당 테스트를 로컬에서 실행할 수 있습니다:
+
+```bash
+python -m pytest -n 8 --dist=loadfile -rA -s $(cat test_list.txt)
+```
+
+잘못된 사항이 누락되었을 경우, 전체 테스트 모음도 매일 실행됩니다.
+
+## 문서 빌드 [[documentation-build]]
+
+`build_pr_documentation` 작업은 문서를 빌드하고 미리 보기를 생성하여 PR이 병합된 후 모든 것이 제대로 보이는지 확인합니다. 로봇은 PR에 문서 미리보기 링크를 추가합니다. PR에서 만든 변경 사항은 자동으로 미리보기에 업데이트됩니다. 문서 빌드에 실패한 경우 **세부 정보**를 클릭하여 어디에서 문제가 발생했는지 확인할 수 있습니다. 오류는 주로 `toctree`에 누락된 파일과 같이 간단한 오류입니다.
+
+로컬에서 문서를 빌드하거나 미리 볼 경우, docs 폴더의 [`README.md`](https://github.com/huggingface/transformers/tree/main/docs)를 참조하세요.
+
+## 코드 및 문서 스타일 [[code-and-documentation-style]]
+
+`black`과 `ruff`를 사용하여 모든 소스 파일, 예제 및 테스트에 코드 형식을 적용합니다. 또한, `utils/style_doc.py`에서 문서 문자열과 `rst` 파일의 형식, 그리고 Transformers의 `__init__.py` 파일에서 실행되는 지연된 임포트의 순서에 대한 사용자 정의 도구가 있습니다. 이 모든 것은 다음을 실행함으로써 실행할 수 있습니다:
+
+```bash
+make style
+```
+
+CI는 이러한 사항이 `ci/circleci: check_code_quality` 검사 내에서 적용되었는지 확인합니다. 또한 `ruff`도 실행되며, 정의되지 않은 변수나 사용되지 않은 변수를 발견하면 경고합니다. 이 검사를 로컬에서 실행하려면 다음을 사용하세요:
+
+```bash
+make quality
+```
+
+이 작업은 많은 시간이 소요될 수 있으므로 현재 브랜치에서 수정한 파일에 대해서만 동일한 작업을 실행하려면 다음을 실행하세요.
+
+```bash
+make fixup
+```
+
+이 명령은 현재 브랜치에서 수정한 파일에 대한 모든 추가적인 검사도 실행합니다. 이제 이들을 살펴보겠습니다.
+
+## 저장소 일관성 [[repository-consistency]]
+
+이는 PR이 저장소를 정상적인 상태로 유지하는지 확인하는 모든 테스트를 모은 것이며, `ci/circleci: check_repository_consistency` 검사에서 수행됩니다. 다음을 실행함으로써 로컬에서 이 검사를 실행할 수 있습니다.
+
+```bash
+make repo-consistency
+```
+
+이 검사는 다음을 확인합니다.
+
+- init에 추가된 모든 객체가 문서화되었는지 (`utils/check_repo.py`에서 수행)
+- `__init__.py` 파일의 두 섹션에 동일한 내용이 있는지 (`utils/check_inits.py`에서 수행)
+- 다른 모듈에서 복사된 코드가 원본과 일치하는지 (`utils/check_copies.py`에서 수행)
+- 모든 구성 클래스에 docstring에 언급된 유효한 체크포인트가 적어도 하나 있는지 (`utils/check_config_docstrings.py`에서 수행)
+- 모든 구성 클래스가 해당하는 모델링 파일에서 사용되는 속성만 포함하고 있는지 (`utils/check_config_attributes.py`에서 수행)
+- README와 문서 인덱스의 번역이 메인 README와 동일한 모델 목록을 가지고 있는지 (`utils/check_copies.py`에서 수행)
+- 문서의 자동 생성된 테이블이 최신 상태인지 (`utils/check_table.py`에서 수행)
+- 라이브러리에는 선택적 종속성이 설치되지 않았더라도 모든 객체가 사용 가능한지 (`utils/check_dummies.py`에서 수행)
+
+이러한 검사가 실패하는 경우, 처음 두 가지 항목은 수동으로 수정해야 하며, 나머지 네 가지 항목은 다음 명령을 실행하여 자동으로 수정할 수 있습니다.
+
+```bash
+make fix-copies
+```
+
+추가적인 검사는 새로운 모델을 추가하는 PR에 대한 것으로, 주로 다음과 같습니다:
+
+- 추가된 모든 모델이 Auto-mapping에 있는지 (`utils/check_repo.py`에서 수행)
+
+- 모든 모델이 올바르게 테스트되었는지 (`utils/check_repo.py`에서 수행)
+
+
+
+### 복사본 확인 [[check-copies]]
+
+Transformers 라이브러리는 모델 코드에 대해 매우 완고하며, 각 모델은 다른 모델에 의존하지 않고 완전히 단일 파일로 구현되어야 합니다. 이렇게 하기 위해 특정 모델의 코드 복사본이 원본과 일관된 상태로 유지되는지 확인하는 메커니즘을 추가했습니다. 따라서 버그 수정이 필요한 경우 다른 모델에 영향을 주는 모든 모델을 볼 수 있으며 수정을 적용할지 수정된 사본을 삭제할지 선택할 수 있습니다.
+
+
+
+파일이 다른 파일의 완전한 사본인 경우 해당 파일을 `utils/check_copies.py`의 `FULL_COPIES` 상수에 등록해야 합니다.
+
+
+
+이 메커니즘은 `# Copied from xxx` 형식의 주석을 기반으로 합니다. `xxx`에는 아래에 복사되는 클래스 또는 함수의 전체 경로가 포함되어야 합니다. 예를 들어 `RobertaSelfOutput`은 `BertSelfOutput` 클래스의 복사본입니다. 따라서 [여기](https://github.com/huggingface/transformers/blob/2bd7a27a671fd1d98059124024f580f8f5c0f3b5/src/transformers/models/roberta/modeling_roberta.py#L289)에서 주석이 있습니다:
+
+
+```py
+# Copied from transformers.models.bert.modeling_bert.BertSelfOutput
+```
+
+클래스 전체에 수정을 적용하는 대신에 복사본과 관련있는 메서드에 적용할 수도 있습니다. 예를 들어 [여기](https://github.com/huggingface/transformers/blob/2bd7a27a671fd1d98059124024f580f8f5c0f3b5/src/transformers/models/roberta/modeling_roberta.py#L598)에서 `RobertaPreTrainedModel._init_weights`가 `BertPreTrainedModel`의 동일한 메서드에서 복사된 것을 볼 수 있으며 해당 주석이 있습니다:
+
+```py
+# Copied from transformers.models.bert.modeling_bert.BertPreTrainedModel._init_weights
+```
+
+복사본이 이름만 다른 경우가 있습니다: 예를 들어 `RobertaAttention`에서 `BertSelfAttention` 대신 `RobertaSelfAttention`을 사용하지만 그 외에는 코드가 완전히 동일합니다: 이 때 `# Copied from`은 `Copied from xxx with foo->bar`와 같은 간단한 문자열 대체를 지원합니다. 이는 모든 `foo` 인스턴스를 `bar`로 바꿔서 코드를 복사합니다. [여기](https://github.com/huggingface/transformers/blob/2bd7a27a671fd1d98059124024f580f8f5c0f3b5/src/transformers/models/roberta/modeling_roberta.py#L304C1-L304C86)에서 어떻게 사용되는지 볼 수 있습니다:
+
+```py
+# Copied from transformers.models.bert.modeling_bert.BertAttention with Bert->Roberta
+```
+
+화살표 주변에는 공백이 없어야 합니다(공백이 대체 패턴의 일부인 경우는 예외입니다).
+
+대체 패턴을 쉼표로 구분하여 여러 패턴을 추가할 수 있습니다. 예를 들어 `CamemberForMaskedLM`은 두 가지 대체 사항을 가진 `RobertaForMaskedLM`의 복사본입니다: `Roberta`를 `Camembert`로 대체하고 `ROBERTA`를 `CAMEMBERT`로 대체합니다. [여기](https://github.com/huggingface/transformers/blob/15082a9dc6950ecae63a0d3e5060b2fc7f15050a/src/transformers/models/camembert/modeling_camembert.py#L929)에서 이것이 주석으로 어떻게 구현되었는지 확인할 수 있습니다:
+
+```py
+# Copied from transformers.models.roberta.modeling_roberta.RobertaForMaskedLM with Roberta->Camembert, ROBERTA->CAMEMBERT
+```
+
+순서가 중요한 경우(이전 수정과 충돌할 수 있는 경우) 수정은 왼쪽에서 오른쪽으로 실행됩니다.
+
+
+
+새 변경이 서식을 변경하는 경우(짧은 이름을 매우 긴 이름으로 바꾸는 경우) 자동 서식 지정기를 적용한 후 복사본이 검사됩니다.
+
+
+
+패턴의 대소문자가 다른 경우(대문자와 소문자가 혼용된 대체 양식) `all-casing` 옵션을 추가하는 방법도 있습니다. [여기](https://github.com/huggingface/transformers/blob/15082a9dc6950ecae63a0d3e5060b2fc7f15050a/src/transformers/models/mobilebert/modeling_mobilebert.py#L1237)에서 `MobileBertForSequenceClassification`에서 사용된 예시를 볼 수 있습니다:
+
+```py
+# Copied from transformers.models.bert.modeling_bert.BertForSequenceClassification with Bert->MobileBert all-casing
+```
+
+이 경우, 코드는 다음과 같이 복사됩니다:
+- `MobileBert`에서 `Bert`로(예: `MobileBertModel`을 init에서 사용할 때)
+- `mobilebert`에서 `bert`로(예: `self.mobilebert`를 정의할 때)
+- `MOBILEBERT`에서 `BERT`로(`MOBILEBERT_INPUTS_DOCSTRING` 상수에서)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/preprocessing.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/preprocessing.md
new file mode 100644
index 0000000000000000000000000000000000000000..4466b63585723d49a5165135c40ec287d25ff907
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/preprocessing.md
@@ -0,0 +1,539 @@
+
+
+# 전처리[[preprocess]]
+
+[[open-in-colab]]
+
+모델을 훈련하려면 데이터 세트를 모델에 맞는 입력 형식으로 전처리해야 합니다. 텍스트, 이미지 또는 오디오인지 관계없이 데이터를 텐서 배치로 변환하고 조립할 필요가 있습니다. 🤗 Transformers는 모델에 대한 데이터를 준비하는 데 도움이 되는 일련의 전처리 클래스를 제공합니다. 이 튜토리얼에서는 다음 내용을 배울 수 있습니다:
+
+* 텍스트는 [Tokenizer](./main_classes/tokenizer)를 사용하여 토큰 시퀀스로 변환하고 토큰의 숫자 표현을 만든 후 텐서로 조립합니다.
+* 음성 및 오디오는 [Feature extractor](./main_classes/feature_extractor)를 사용하여 오디오 파형에서 시퀀스 특성을 파악하여 텐서로 변환합니다.
+* 이미지 입력은 [ImageProcessor](./main_classes/image)을 사용하여 이미지를 텐서로 변환합니다.
+* 멀티모달 입력은 [Processor](./main_classes/processors)을 사용하여 토크나이저와 특성 추출기 또는 이미지 프로세서를 결합합니다.
+
+
+
+`AutoProcessor`는 **언제나** 작동하여 토크나이저, 이미지 프로세서, 특성 추출기 또는 프로세서 등 사용 중인 모델에 맞는 클래스를 자동으로 선택합니다.
+
+
+
+시작하기 전에 🤗 Datasets를 설치하여 실험에 사용할 데이터를 불러올 수 있습니다:
+
+```bash
+pip install datasets
+```
+
+## 자연어처리[[natural-language-processing]]
+
+
+
+사전훈련된 모델을 사용할 계획이라면 모델과 함께 사전훈련된 토크나이저를 사용하는 것이 중요합니다. 이렇게 하면 텍스트가 사전훈련 말뭉치와 동일한 방식으로 분할되고 사전훈련 중에 동일한 해당 토큰-인덱스 쌍(일반적으로 *vocab*이라고 함)을 사용합니다.
+
+
+
+시작하려면 [`AutoTokenizer.from_pretrained`] 메소드를 사용하여 사전훈련된 토크나이저를 불러오세요. 모델과 함께 사전훈련된 *vocab*을 다운로드합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-cased")
+```
+
+그 다음으로 텍스트를 토크나이저에 넣어주세요:
+
+```py
+>>> encoded_input = tokenizer("Do not meddle in the affairs of wizards, for they are subtle and quick to anger.")
+>>> print(encoded_input)
+{'input_ids': [101, 2079, 2025, 19960, 10362, 1999, 1996, 3821, 1997, 16657, 1010, 2005, 2027, 2024, 11259, 1998, 4248, 2000, 4963, 1012, 102],
+ 'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+토크나이저는 세 가지 중요한 항목을 포함한 딕셔너리를 반환합니다:
+
+* [input_ids](glossary#input-ids)는 문장의 각 토큰에 해당하는 인덱스입니다.
+* [attention_mask](glossary#attention-mask)는 토큰을 처리해야 하는지 여부를 나타냅니다.
+* [token_type_ids](glossary#token-type-ids)는 두 개 이상의 시퀀스가 있을 때 토큰이 속한 시퀀스를 식별합니다.
+
+`input_ids`를 디코딩하여 입력을 반환합니다:
+
+```py
+>>> tokenizer.decode(encoded_input["input_ids"])
+'[CLS] Do not meddle in the affairs of wizards, for they are subtle and quick to anger. [SEP]'
+```
+
+토크나이저가 두 개의 특수한 토큰(분류 토큰 `CLS`와 분할 토큰 `SEP`)을 문장에 추가했습니다.
+모든 모델에 특수한 토큰이 필요한 것은 아니지만, 필요하다면 토크나이저가 자동으로 추가합니다.
+
+전처리할 문장이 여러 개 있는 경우에는 리스트로 토크나이저에 전달합니다:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_inputs = tokenizer(batch_sentences)
+>>> print(encoded_inputs)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1]]}
+```
+
+### 패딩[[pad]]
+
+모델 입력인 텐서는 모양이 균일해야 하지만, 문장의 길이가 항상 같지는 않기 때문에 문제가 될 수 있습니다. 패딩은 짧은 문장에 특수한 *패딩 토큰*을 추가하여 텐서를 직사각형 모양이 되도록 하는 전략입니다.
+
+`padding` 매개변수를 `True`로 설정하여 배치 내의 짧은 시퀀스를 가장 긴 시퀀스에 맞춰 패딩합니다.
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True)
+>>> print(encoded_input)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]]}
+```
+
+길이가 짧은 첫 문장과 세 번째 문장이 이제 `0`으로 채워졌습니다.
+
+### 잘라내기[[truncation]]
+
+한편, 때로는 시퀀스가 모델에서 처리하기에 너무 길 수도 있습니다. 이 경우, 시퀀스를 더 짧게 줄일 필요가 있습니다.
+
+모델에서 허용하는 최대 길이로 시퀀스를 자르려면 `truncation` 매개변수를 `True`로 설정하세요:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True)
+>>> print(encoded_input)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]]}
+```
+
+
+
+다양한 패딩과 잘라내기 인수에 대해 더 알아보려면 [패딩과 잘라내기](./pad_truncation) 개념 가이드를 확인해보세요.
+
+
+
+### 텐서 만들기[[build-tensors]]
+
+마지막으로, 토크나이저가 모델에 공급되는 실제 텐서를 반환하도록 합니다.
+
+`return_tensors` 매개변수를 PyTorch의 경우 `pt`, TensorFlow의 경우 `tf`로 설정하세요:
+
+
+
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True, return_tensors="pt")
+>>> print(encoded_input)
+{'input_ids': tensor([[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]]),
+ 'token_type_ids': tensor([[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]]),
+ 'attention_mask': tensor([[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]])}
+```
+
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True, return_tensors="tf")
+>>> print(encoded_input)
+{'input_ids': ,
+ 'token_type_ids': ,
+ 'attention_mask': }
+```
+
+
+
+## 오디오[[audio]]
+
+오디오 작업은 모델에 맞는 데이터 세트를 준비하기 위해 [특성 추출기](main_classes/feature_extractor)가 필요합니다. 특성 추출기는 원시 오디오 데이터에서 특성를 추출하고 이를 텐서로 변환하는 것이 목적입니다.
+
+오디오 데이터 세트에 특성 추출기를 사용하는 방법을 보기 위해 [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) 데이터 세트를 가져오세요. (데이터 세트를 가져오는 방법은 🤗 [데이터 세트 튜토리얼](https://huggingface.co/docs/datasets/load_hub)에서 자세히 설명하고 있습니다.)
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train")
+```
+
+`audio` 열의 첫 번째 요소에 접근하여 입력을 살펴보세요. `audio` 열을 호출하면 오디오 파일을 자동으로 가져오고 리샘플링합니다.
+
+```py
+>>> dataset[0]["audio"]
+{'array': array([ 0. , 0.00024414, -0.00024414, ..., -0.00024414,
+ 0. , 0. ], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~JOINT_ACCOUNT/602ba55abb1e6d0fbce92065.wav',
+ 'sampling_rate': 8000}
+```
+
+이렇게 하면 세 가지 항목이 반환됩니다:
+
+* `array`는 1D 배열로 가져와서 (필요한 경우) 리샘플링된 음성 신호입니다.
+* `path`는 오디오 파일의 위치를 가리킵니다.
+* `sampling_rate`는 음성 신호에서 초당 측정되는 데이터 포인트 수를 나타냅니다.
+
+이 튜토리얼에서는 [Wav2Vec2](https://huggingface.co/facebook/wav2vec2-base) 모델을 사용합니다. 모델 카드를 보면 Wav2Vec2가 16kHz 샘플링된 음성 오디오를 기반으로 사전훈련된 것을 알 수 있습니다.
+모델을 사전훈련하는 데 사용된 데이터 세트의 샘플링 레이트와 오디오 데이터의 샘플링 레이트가 일치해야 합니다. 데이터의 샘플링 레이트가 다르면 데이터를 리샘플링해야 합니다.
+
+1. 🤗 Datasets의 [`~datasets.Dataset.cast_column`] 메소드를 사용하여 샘플링 레이트를 16kHz로 업샘플링하세요:
+
+```py
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16_000))
+```
+
+2. 오디오 파일을 리샘플링하기 위해 `audio` 열을 다시 호출합니다:
+
+```py
+>>> dataset[0]["audio"]
+{'array': array([ 2.3443763e-05, 2.1729663e-04, 2.2145823e-04, ...,
+ 3.8356509e-05, -7.3497440e-06, -2.1754686e-05], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~JOINT_ACCOUNT/602ba55abb1e6d0fbce92065.wav',
+ 'sampling_rate': 16000}
+```
+
+다음으로, 입력을 정규화하고 패딩할 특성 추출기를 가져오세요. 텍스트 데이터의 경우, 더 짧은 시퀀스에 대해 `0`이 추가됩니다. 오디오 데이터에도 같은 개념이 적용됩니다.
+특성 추출기는 배열에 `0`(묵음으로 해석)을 추가합니다.
+
+[`AutoFeatureExtractor.from_pretrained`]를 사용하여 특성 추출기를 가져오세요:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2-base")
+```
+
+오디오 `array`를 특성 추출기에 전달하세요. 또한, 발생할 수 있는 조용한 오류(silent errors)를 더 잘 디버깅할 수 있도록 특성 추출기에 `sampling_rate` 인수를 추가하는 것을 권장합니다.
+
+```py
+>>> audio_input = [dataset[0]["audio"]["array"]]
+>>> feature_extractor(audio_input, sampling_rate=16000)
+{'input_values': [array([ 3.8106556e-04, 2.7506407e-03, 2.8015103e-03, ...,
+ 5.6335266e-04, 4.6588284e-06, -1.7142107e-04], dtype=float32)]}
+```
+
+토크나이저와 마찬가지로 배치 내에서 가변적인 시퀀스를 처리하기 위해 패딩 또는 잘라내기를 적용할 수 있습니다. 이 두 개의 오디오 샘플의 시퀀스 길이를 확인해보세요:
+
+```py
+>>> dataset[0]["audio"]["array"].shape
+(173398,)
+
+>>> dataset[1]["audio"]["array"].shape
+(106496,)
+```
+
+오디오 샘플의 길이가 동일하도록 데이터 세트를 전처리하는 함수를 만드세요. 최대 샘플 길이를 지정하면 특성 추출기가 해당 길이에 맞춰 시퀀스를 패딩하거나 잘라냅니다:
+
+```py
+>>> def preprocess_function(examples):
+... audio_arrays = [x["array"] for x in examples["audio"]]
+... inputs = feature_extractor(
+... audio_arrays,
+... sampling_rate=16000,
+... padding=True,
+... max_length=100000,
+... truncation=True,
+... )
+... return inputs
+```
+
+`preprocess_function`을 데이터 세트의 처음 예시 몇 개에 적용해보세요:
+
+```py
+>>> processed_dataset = preprocess_function(dataset[:5])
+```
+
+이제 샘플 길이가 모두 같고 지정된 최대 길이에 맞게 되었습니다. 드디어 전처리된 데이터 세트를 모델에 전달할 수 있습니다!
+
+```py
+>>> processed_dataset["input_values"][0].shape
+(100000,)
+
+>>> processed_dataset["input_values"][1].shape
+(100000,)
+```
+
+## 컴퓨터 비전[[computer-vision]]
+
+컴퓨터 비전 작업의 경우, 모델에 대한 데이터 세트를 준비하기 위해 [이미지 프로세서](main_classes/image_processor)가 필요합니다.
+이미지 전처리는 이미지를 모델이 예상하는 입력으로 변환하는 여러 단계로 이루어집니다.
+이러한 단계에는 크기 조정, 정규화, 색상 채널 보정, 이미지의 텐서 변환 등이 포함됩니다.
+
+
+
+이미지 전처리는 이미지 증강 기법을 몇 가지 적용한 뒤에 할 수도 있습니다.
+이미지 전처리 및 이미지 증강은 모두 이미지 데이터를 변형하지만, 서로 다른 목적을 가지고 있습니다:
+
+* 이미지 증강은 과적합(over-fitting)을 방지하고 모델의 견고함(resiliency)을 높이는 데 도움이 되는 방식으로 이미지를 수정합니다.
+밝기와 색상 조정, 자르기, 회전, 크기 조정, 확대/축소 등 다양한 방법으로 데이터를 증강할 수 있습니다.
+그러나 증강으로 이미지의 의미가 바뀌지 않도록 주의해야 합니다.
+* 이미지 전처리는 이미지가 모델이 예상하는 입력 형식과 일치하도록 보장합니다.
+컴퓨터 비전 모델을 미세 조정할 때 이미지는 모델이 초기에 훈련될 때와 정확히 같은 방식으로 전처리되어야 합니다.
+
+이미지 증강에는 원하는 라이브러리를 무엇이든 사용할 수 있습니다. 이미지 전처리에는 모델과 연결된 `ImageProcessor`를 사용합니다.
+
+
+
+[food101](https://huggingface.co/datasets/food101) 데이터 세트를 가져와서 컴퓨터 비전 데이터 세트에서 이미지 프로세서를 어떻게 사용하는지 알아보세요.
+데이터 세트를 불러오는 방법은 🤗 [데이터 세트 튜토리얼](https://huggingface.co/docs/datasets/load_hub)을 참고하세요.
+
+
+
+데이터 세트가 상당히 크기 때문에 🤗 Datasets의 `split` 매개변수를 사용하여 훈련 세트에서 작은 샘플만 가져오세요!
+
+
+
+```py
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("food101", split="train[:100]")
+```
+
+다음으로, 🤗 Datasets의 [`image`](https://huggingface.co/docs/datasets/package_reference/main_classes?highlight=image#datasets.Image)로 이미지를 확인해보세요:
+
+```py
+>>> dataset[0]["image"]
+```
+
+
+
+
+
+위의 예에서는 이미지 증강 중에 이미지 크기를 조정했기 때문에 `do_resize=False`로 설정하고, 해당 `image_processor`에서 `size` 속성을 활용했습니다.
+이미지 증강 중에 이미지 크기를 조정하지 않은 경우 이 매개변수를 생략하세요.
+기본적으로는 `ImageProcessor`가 크기 조정을 처리합니다.
+
+증강 변환 과정에서 이미지를 정규화하려면 `image_processor.image_mean` 및 `image_processor.image_std` 값을 사용하세요.
+
+
+
+3. 🤗 Datasets의 [`set_transform`](https://huggingface.co/docs/datasets/process#format-transform)를 사용하여 실시간으로 변환을 적용합니다:
+
+```py
+>>> dataset.set_transform(transforms)
+```
+
+4. 이제 이미지에 접근하면 이미지 프로세서가 `pixel_values`를 추가한 것을 알 수 있습니다.
+드디어 처리된 데이터 세트를 모델에 전달할 수 있습니다!
+
+```py
+>>> dataset[0].keys()
+```
+
+다음은 변형이 적용된 후의 이미지입니다. 이미지가 무작위로 잘려나갔고 색상 속성이 다릅니다.
+
+```py
+>>> import numpy as np
+>>> import matplotlib.pyplot as plt
+
+>>> img = dataset[0]["pixel_values"]
+>>> plt.imshow(img.permute(1, 2, 0))
+```
+
+
+
+
+
+`ImageProcessor`는 객체 감지, 시맨틱 세그멘테이션(semantic segmentation), 인스턴스 세그멘테이션(instance segmentation), 파놉틱 세그멘테이션(panoptic segmentation)과 같은 작업에 대한 후처리 방법을 제공합니다.
+이러한 방법은 모델의 원시 출력을 경계 상자나 세그멘테이션 맵과 같은 의미 있는 예측으로 변환해줍니다.
+
+
+
+### 패딩[[pad]]
+
+예를 들어, [DETR](./model_doc/detr)와 같은 경우에는 모델이 훈련할 때 크기 조정 증강을 적용합니다.
+이로 인해 배치 내 이미지 크기가 달라질 수 있습니다.
+[`DetrImageProcessor`]의 [`DetrImageProcessor.pad`]를 사용하고 사용자 정의 `collate_fn`을 정의해서 배치 이미지를 처리할 수 있습니다.
+
+```py
+>>> def collate_fn(batch):
+... pixel_values = [item["pixel_values"] for item in batch]
+... encoding = image_processor.pad(pixel_values, return_tensors="pt")
+... labels = [item["labels"] for item in batch]
+... batch = {}
+... batch["pixel_values"] = encoding["pixel_values"]
+... batch["pixel_mask"] = encoding["pixel_mask"]
+... batch["labels"] = labels
+... return batch
+```
+
+## 멀티모달[[multimodal]]
+
+멀티모달 입력이 필요한 작업의 경우, 모델에 데이터 세트를 준비하기 위한 [프로세서](main_classes/processors)가 필요합니다.
+프로세서는 토크나이저와 특성 추출기와 같은 두 가지 처리 객체를 결합합니다.
+
+[LJ Speech](https://huggingface.co/datasets/lj_speech) 데이터 세트를 가져와서 자동 음성 인식(ASR)을 위한 프로세서를 사용하는 방법을 확인하세요.
+(데이터 세트를 가져오는 방법에 대한 자세한 내용은 🤗 [데이터 세트 튜토리얼](https://huggingface.co/docs/datasets/load_hub)에서 볼 수 있습니다.)
+
+```py
+>>> from datasets import load_dataset
+
+>>> lj_speech = load_dataset("lj_speech", split="train")
+```
+
+자동 음성 인식(ASR)에서는 `audio`와 `text`에만 집중하면 되므로, 다른 열들은 제거할 수 있습니다:
+
+```py
+>>> lj_speech = lj_speech.map(remove_columns=["file", "id", "normalized_text"])
+```
+
+이제 `audio`와 `text`열을 살펴보세요:
+
+```py
+>>> lj_speech[0]["audio"]
+{'array': array([-7.3242188e-04, -7.6293945e-04, -6.4086914e-04, ...,
+ 7.3242188e-04, 2.1362305e-04, 6.1035156e-05], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/917ece08c95cf0c4115e45294e3cd0dee724a1165b7fc11798369308a465bd26/LJSpeech-1.1/wavs/LJ001-0001.wav',
+ 'sampling_rate': 22050}
+
+>>> lj_speech[0]["text"]
+'Printing, in the only sense with which we are at present concerned, differs from most if not from all the arts and crafts represented in the Exhibition'
+```
+
+기존에 사전훈련된 모델에서 사용된 데이터 세트와 새로운 오디오 데이터 세트의 샘플링 레이트를 일치시키기 위해 오디오 데이터 세트의 샘플링 레이트를 [리샘플링](preprocessing#audio)해야 합니다!
+
+```py
+>>> lj_speech = lj_speech.cast_column("audio", Audio(sampling_rate=16_000))
+```
+
+[`AutoProcessor.from_pretrained`]로 프로세서를 가져오세요:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base-960h")
+```
+
+1. `array`에 들어 있는 오디오 데이터를 `input_values`로 변환하고 `text`를 토큰화하여 `labels`로 변환하는 함수를 만듭니다.
+모델의 입력은 다음과 같습니다:
+
+```py
+>>> def prepare_dataset(example):
+... audio = example["audio"]
+
+... example.update(processor(audio=audio["array"], text=example["text"], sampling_rate=16000))
+
+... return example
+```
+
+2. 샘플을 `prepare_dataset` 함수에 적용하세요:
+
+```py
+>>> prepare_dataset(lj_speech[0])
+```
+
+이제 프로세서가 `input_values`와 `labels`를 추가하고, 샘플링 레이트도 올바르게 16kHz로 다운샘플링했습니다.
+드디어 처리된 데이터 세트를 모델에 전달할 수 있습니다!
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/quantization/awq.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/quantization/awq.md
new file mode 100644
index 0000000000000000000000000000000000000000..3855b42a73525ab9bebbb15d37df9070f1ffa143
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/quantization/awq.md
@@ -0,0 +1,233 @@
+
+
+# AWQ [[awq]]
+
+
+
+이 [노트북](https://colab.research.google.com/drive/1HzZH89yAXJaZgwJDhQj9LqSBux932BvY) 으로 AWQ 양자화를 실습해보세요 !
+
+
+
+[Activation-aware Weight Quantization (AWQ)](https://hf.co/papers/2306.00978)은 모델의 모든 가중치를 양자화하지 않고, LLM 성능에 중요한 가중치를 유지합니다. 이로써 4비트 정밀도로 모델을 실행해도 성능 저하 없이 양자화 손실을 크게 줄일 수 있습니다.
+
+AWQ 알고리즘을 사용하여 모델을 양자화할 수 있는 여러 라이브러리가 있습니다. 예를 들어 [llm-awq](https://github.com/mit-han-lab/llm-awq), [autoawq](https://github.com/casper-hansen/AutoAWQ) , [optimum-intel](https://huggingface.co/docs/optimum/main/en/intel/optimization_inc) 등이 있습니다. Transformers는 llm-awq, autoawq 라이브러리를 이용해 양자화된 모델을 가져올 수 있도록 지원합니다. 이 가이드에서는 autoawq로 양자화된 모델을 가져오는 방법을 보여드리나, llm-awq로 양자화된 모델의 경우도 유사한 절차를 따릅니다.
+
+autoawq가 설치되어 있는지 확인하세요:
+
+```bash
+pip install autoawq
+```
+
+AWQ 양자화된 모델은 해당 모델의 [config.json](https://huggingface.co/TheBloke/zephyr-7B-alpha-AWQ/blob/main/config.json) 파일의 `quantization_config` 속성을 통해 식별할 수 있습니다.:
+
+```json
+{
+ "_name_or_path": "/workspace/process/huggingfaceh4_zephyr-7b-alpha/source",
+ "architectures": [
+ "MistralForCausalLM"
+ ],
+ ...
+ ...
+ ...
+ "quantization_config": {
+ "quant_method": "awq",
+ "zero_point": true,
+ "group_size": 128,
+ "bits": 4,
+ "version": "gemm"
+ }
+}
+```
+
+양자화된 모델은 [`~PreTrainedModel.from_pretrained`] 메서드를 사용하여 가져옵니다. 모델을 CPU에 가져왔다면, 먼저 모델을 GPU 장치로 옮겨야 합니다. `device_map` 파라미터를 사용하여 모델을 배치할 위치를 지정하세요:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_id = "TheBloke/zephyr-7B-alpha-AWQ"
+model = AutoModelForCausalLM.from_pretrained(model_id, device_map="cuda:0")
+```
+
+AWQ 양자화 모델을 가져오면 자동으로 성능상의 이유로 인해 가중치들의 기본값이 fp16으로 설정됩니다. 가중치를 다른 형식으로 가져오려면, `torch_dtype` 파라미터를 사용하세요:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_id = "TheBloke/zephyr-7B-alpha-AWQ"
+model = AutoModelForCausalLM.from_pretrained(model_id, torch_dtype=torch.float32)
+```
+
+추론을 더욱 가속화하기 위해 AWQ 양자화와 [FlashAttention-2](../perf_infer_gpu_one#flashattention-2) 를 결합 할 수 있습니다:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained("TheBloke/zephyr-7B-alpha-AWQ", attn_implementation="flash_attention_2", device_map="cuda:0")
+```
+
+## 퓨즈된 모듈 [[fused-modules]]
+
+퓨즈된 모듈은 정확도와 성능을 개선합니다. 퓨즈된 모듈은 [Llama](https://huggingface.co/meta-llama) 아키텍처와 [Mistral](https://huggingface.co/mistralai/Mistral-7B-v0.1) 아키텍처의 AWQ모듈에 기본적으로 지원됩니다. 그러나 지원되지 않는 아키텍처에 대해서도 AWQ 모듈을 퓨즈할 수 있습니다.
+
+
+
+퓨즈된 모듈은 FlashAttention-2와 같은 다른 최적화 기술과 결합할 수 없습니다.
+
+
+
+
+
+
+
+지원되는 아키텍처에서 퓨즈된 모듈을 활성화하려면, [`AwqConfig`] 를 생성하고 매개변수 `fuse_max_seq_len` 과 `do_fuse=True`를 설정해야 합니다. `fuse_max_seq_len` 매개변수는 전체 시퀀스 길이로, 컨텍스트 길이와 예상 생성 길이를 포함해야 합니다. 안전하게 사용하기 위해 더 큰 값으로 설정할 수 있습니다.
+
+예를 들어, [TheBloke/Mistral-7B-OpenOrca-AWQ](https://huggingface.co/TheBloke/Mistral-7B-OpenOrca-AWQ) 모델의 AWQ 모듈을 퓨즈해보겠습니다.
+
+```python
+import torch
+from transformers import AwqConfig, AutoModelForCausalLM
+
+model_id = "TheBloke/Mistral-7B-OpenOrca-AWQ"
+
+quantization_config = AwqConfig(
+ bits=4,
+ fuse_max_seq_len=512,
+ do_fuse=True,
+)
+
+model = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=quantization_config).to(0)
+```
+
+[TheBloke/Mistral-7B-OpenOrca-AWQ](https://huggingface.co/TheBloke/Mistral-7B-OpenOrca-AWQ) 모델은 퓨즈된 모듈이 있는 경우와 없는 경우 모두 `batch_size=1` 로 성능 평가되었습니다.
+
+퓨즈되지 않은 모듈
+
+| 배치 크기 | 프리필 길이 | 디코드 길이 | 프리필 토큰/초 | 디코드 토큰/초 | 메모리 (VRAM) |
+|-------------:|-----------------:|----------------:|-------------------:|------------------:|:----------------|
+| 1 | 32 | 32 | 60.0984 | 38.4537 | 4.50 GB (5.68%) |
+| 1 | 64 | 64 | 1333.67 | 31.6604 | 4.50 GB (5.68%) |
+| 1 | 128 | 128 | 2434.06 | 31.6272 | 4.50 GB (5.68%) |
+| 1 | 256 | 256 | 3072.26 | 38.1731 | 4.50 GB (5.68%) |
+| 1 | 512 | 512 | 3184.74 | 31.6819 | 4.59 GB (5.80%) |
+| 1 | 1024 | 1024 | 3148.18 | 36.8031 | 4.81 GB (6.07%) |
+| 1 | 2048 | 2048 | 2927.33 | 35.2676 | 5.73 GB (7.23%) |
+
+퓨즈된 모듈
+
+| 배치 크기 | 프리필 길이 | 디코드 길이 | 프리필 토큰/초 | 디코드 토큰/초 | 메모리 (VRAM) |
+|-------------:|-----------------:|----------------:|-------------------:|------------------:|:----------------|
+| 1 | 32 | 32 | 81.4899 | 80.2569 | 4.00 GB (5.05%) |
+| 1 | 64 | 64 | 1756.1 | 106.26 | 4.00 GB (5.05%) |
+| 1 | 128 | 128 | 2479.32 | 105.631 | 4.00 GB (5.06%) |
+| 1 | 256 | 256 | 1813.6 | 85.7485 | 4.01 GB (5.06%) |
+| 1 | 512 | 512 | 2848.9 | 97.701 | 4.11 GB (5.19%) |
+| 1 | 1024 | 1024 | 3044.35 | 87.7323 | 4.41 GB (5.57%) |
+| 1 | 2048 | 2048 | 2715.11 | 89.4709 | 5.57 GB (7.04%) |
+
+퓨즈된 모듈 및 퓨즈되지 않은 모듈의 속도와 처리량은 [optimum-benchmark](https://github.com/huggingface/optimum-benchmark)라이브러리를 사용하여 테스트 되었습니다.
+
+
+
+
+
포워드 피크 메모리 (forward peak memory)/배치 크기
+
+
+
+
생성 처리량/배치크기
+
+
+
+
+퓨즈된 모듈을 지원하지 않는 아키텍처의 경우, `modules_to_fuse` 매개변수를 사용해 직접 퓨즈 매핑을 만들어 어떤 모듈을 퓨즈할지 정의해야합니다. 예로, [TheBloke/Yi-34B-AWQ](https://huggingface.co/TheBloke/Yi-34B-AWQ) 모델의 AWQ 모듈을 퓨즈하는 방법입니다.
+
+```python
+import torch
+from transformers import AwqConfig, AutoModelForCausalLM
+
+model_id = "TheBloke/Yi-34B-AWQ"
+
+quantization_config = AwqConfig(
+ bits=4,
+ fuse_max_seq_len=512,
+ modules_to_fuse={
+ "attention": ["q_proj", "k_proj", "v_proj", "o_proj"],
+ "layernorm": ["ln1", "ln2", "norm"],
+ "mlp": ["gate_proj", "up_proj", "down_proj"],
+ "use_alibi": False,
+ "num_attention_heads": 56,
+ "num_key_value_heads": 8,
+ "hidden_size": 7168
+ }
+)
+
+model = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=quantization_config).to(0)
+```
+
+ `modules_to_fuse` 매개변수는 다음을 포함해야 합니다:
+
+- `"attention"`: 어텐션 레이어는 다음 순서로 퓨즈하세요 : 쿼리 (query), 키 (key), 값 (value) , 출력 프로젝션 계층 (output projection layer). 해당 레이어를 퓨즈하지 않으려면 빈 리스트를 전달하세요.
+- `"layernorm"`: 사용자 정의 퓨즈 레이어 정규화로 교할 레이어 정규화 레이어명. 해당 레이어를 퓨즈하지 않으려면 빈 리스트를 전달하세요.
+- `"mlp"`: 단일 MLP 레이어로 퓨즈할 MLP 레이어 순서 : (게이트 (gate) (덴스(dense), 레이어(layer), 포스트 어텐션(post-attention)) / 위 / 아래 레이어).
+- `"use_alibi"`: 모델이 ALiBi positional embedding을 사용할 경우 설정합니다.
+- `"num_attention_heads"`: 어텐션 헤드 (attention heads)의 수를 설정합니다.
+- `"num_key_value_heads"`: 그룹화 쿼리 어텐션 (GQA)을 구현하는데 사용되는 키 값 헤드의 수를 설정합니다. `num_key_value_heads=num_attention_heads`로 설정할 경우, 모델은 다중 헤드 어텐션 (MHA)가 사용되며, `num_key_value_heads=1` 는 다중 쿼리 어텐션 (MQA)가, 나머지는 GQA가 사용됩니다.
+- `"hidden_size"`: 숨겨진 표현(hidden representations)의 차원을 설정합니다.
+
+
+
+
+
+
+## ExLlama-v2 서포트 [[exllama-v2-support]]
+
+최신 버전 `autoawq`는 빠른 프리필과 디코딩을 위해 ExLlama-v2 커널을 지원합니다. 시작하기 위해 먼저 최신 버전 `autoawq` 를 설치하세요 :
+
+```bash
+pip install git+https://github.com/casper-hansen/AutoAWQ.git
+```
+
+매개변수를 `version="exllama"`로 설정해 `AwqConfig()`를 생성하고 모델에 넘겨주세요.
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, AwqConfig
+
+quantization_config = AwqConfig(version="exllama")
+
+model = AutoModelForCausalLM.from_pretrained(
+ "TheBloke/Mistral-7B-Instruct-v0.1-AWQ",
+ quantization_config=quantization_config,
+ device_map="auto",
+)
+
+input_ids = torch.randint(0, 100, (1, 128), dtype=torch.long, device="cuda")
+output = model(input_ids)
+print(output.logits)
+
+tokenizer = AutoTokenizer.from_pretrained("TheBloke/Mistral-7B-Instruct-v0.1-AWQ")
+input_ids = tokenizer.encode("How to make a cake", return_tensors="pt").to(model.device)
+output = model.generate(input_ids, do_sample=True, max_length=50, pad_token_id=50256)
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+이 기능은 AMD GPUs에서 지원됩니다.
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/quantization/bitsandbytes.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/quantization/bitsandbytes.md
new file mode 100644
index 0000000000000000000000000000000000000000..f0420c2869ea13e104980c1847ac765909e0f1cd
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/quantization/bitsandbytes.md
@@ -0,0 +1,307 @@
+
+
+# bitsandbytes [[bitsandbytes]]
+
+[bitsandbytes](https://github.com/TimDettmers/bitsandbytes)는 모델을 8비트 및 4비트로 양자화하는 가장 쉬운 방법입니다. 8비트 양자화는 fp16의 이상치와 int8의 비이상치를 곱한 후, 비이상치 값을 fp16으로 다시 변환하고, 이들을 합산하여 fp16으로 가중치를 반환합니다. 이렇게 하면 이상치 값이 모델 성능에 미치는 저하 효과를 줄일 수 있습니다. 4비트 양자화는 모델을 더욱 압축하며, [QLoRA](https://hf.co/papers/2305.14314)와 함께 사용하여 양자화된 대규모 언어 모델을 미세 조정하는 데 흔히 사용됩니다.
+
+bitsandbytes를 사용하려면 다음 라이브러리가 설치되어 있어야 합니다:
+
+
+
+
+```bash
+pip install transformers accelerate bitsandbytes>0.37.0
+```
+
+
+
+
+```bash
+pip install bitsandbytes>=0.39.0
+pip install --upgrade accelerate transformers
+```
+
+
+
+
+이제 `BitsAndBytesConfig`를 [`~PreTrainedModel.from_pretrained`] 메소드에 전달하여 모델을 양자화할 수 있습니다. 이는 Accelerate 가져오기를 지원하고 `torch.nn.Linear` 레이어가 포함된 모든 모델에서 작동합니다.
+
+
+
+
+모델을 8비트로 양자화하면 메모리 사용량이 절반으로 줄어들며, 대규모 모델의 경우 사용 가능한 GPU를 효율적으로 활용하려면 `device_map="auto"`를 설정하세요.
+
+```py
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_8bit=True)
+
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ "bigscience/bloom-1b7",
+ quantization_config=quantization_config
+)
+```
+
+기본적으로 `torch.nn.LayerNorm`과 같은 다른 모듈은 `torch.float16`으로 변환됩니다. 원한다면 `torch_dtype` 매개변수로 이들 모듈의 데이터 유형을 변경할 수 있습니다:
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_8bit=True)
+
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ "facebook/opt-350m",
+ quantization_config=quantization_config,
+ torch_dtype=torch.float32
+)
+model_8bit.model.decoder.layers[-1].final_layer_norm.weight.dtype
+```
+
+모델이 8비트로 양자화되면 최신 버전의 Transformers와 bitsandbytes를 사용하지 않는 한 양자화된 가중치를 Hub에 푸시할 수 없습니다. 최신 버전을 사용하는 경우, [`~PreTrainedModel.push_to_hub`] 메소드를 사용하여 8비트 모델을 Hub에 푸시할 수 있습니다. 양자화 config.json 파일이 먼저 푸시되고, 그 다음 양자화된 모델 가중치가 푸시됩니다.
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_8bit=True)
+
+model = AutoModelForCausalLM.from_pretrained(
+ "bigscience/bloom-560m",
+ quantization_config=quantization_config
+)
+tokenizer = AutoTokenizer.from_pretrained("bigscience/bloom-560m")
+
+model.push_to_hub("bloom-560m-8bit")
+```
+
+
+
+
+모델을 4비트로 양자화하면 메모리 사용량이 4배 줄어들며, 대규모 모델의 경우 사용 가능한 GPU를 효율적으로 활용하려면 `device_map="auto"`를 설정하세요:
+
+```py
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_4bit=True)
+
+model_4bit = AutoModelForCausalLM.from_pretrained(
+ "bigscience/bloom-1b7",
+ quantization_config=quantization_config
+)
+```
+
+기본적으로 `torch.nn.LayerNorm`과 같은 다른 모듈은 `torch.float16`으로 변환됩니다. 원한다면 `torch_dtype` 매개변수로 이들 모듈의 데이터 유형을 변경할 수 있습니다:
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_4bit=True)
+
+model_4bit = AutoModelForCausalLM.from_pretrained(
+ "facebook/opt-350m",
+ quantization_config=quantization_config,
+ torch_dtype=torch.float32
+)
+model_4bit.model.decoder.layers[-1].final_layer_norm.weight.dtype
+```
+
+`bitsandbytes>=0.41.3`을 사용하는 경우 4비트 모델을 직렬화하고 Hugging Face Hub에 푸시할 수 있습니다. 모델을 4비트 정밀도로 가져온 후 `model.push_to_hub()`를 호출하면 됩니다. 또한 `model.save_pretrained()` 명령어로 로컬에 직렬화된 4비트 모델을 저장할 수도 있습니다.
+
+
+
+
+
+
+8비트 및 4비트 가중치로 훈련하는 것은 *추가* 매개변수에 대해서만 지원됩니다.
+
+
+
+메모리 사용량을 확인하려면 `get_memory_footprint`를 사용하세요:
+
+```py
+print(model.get_memory_footprint())
+```
+
+양자화된 모델은 [`~PreTrainedModel.from_pretrained`] 메소드를 사용하여 `load_in_8bit` 또는 `load_in_4bit` 매개변수를 지정하지 않고도 가져올 수 있습니다:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained("{your_username}/bloom-560m-8bit", device_map="auto")
+```
+
+## 8비트 (LLM.int8() 알고리즘)[[8-bit-(llm.int8()-algorithm)]]
+
+
+
+8비트 양자화에 대한 자세한 내용을 알고 싶다면 이 [블로그 포스트](https://huggingface.co/blog/hf-bitsandbytes-integration)를 참조하세요!
+
+
+
+이 섹션에서는 오프로딩, 이상치 임곗값, 모듈 변환 건너뛰기 및 미세 조정과 같은 8비트 모델의 특정 기능을 살펴봅니다.
+
+### 오프로딩 [[offloading]]
+
+8비트 모델은 CPU와 GPU 간에 가중치를 오프로드하여 매우 큰 모델을 메모리에 장착할 수 있습니다. CPU로 전송된 가중치는 실제로 **float32**로 저장되며 8비트로 변환되지 않습니다. 예를 들어, [bigscience/bloom-1b7](https://huggingface.co/bigscience/bloom-1b7) 모델의 오프로드를 활성화하려면 [`BitsAndBytesConfig`]를 생성하는 것부터 시작하세요:
+
+```py
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(llm_int8_enable_fp32_cpu_offload=True)
+```
+
+CPU에 전달할 `lm_head`를 제외한 모든 것을 GPU에 적재할 수 있도록 사용자 정의 디바이스 맵을 설계합니다:
+
+```py
+device_map = {
+ "transformer.word_embeddings": 0,
+ "transformer.word_embeddings_layernorm": 0,
+ "lm_head": "cpu",
+ "transformer.h": 0,
+ "transformer.ln_f": 0,
+}
+```
+
+이제 사용자 정의 `device_map`과 `quantization_config`을 사용하여 모델을 가져옵니다:
+
+```py
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ "bigscience/bloom-1b7",
+ device_map=device_map,
+ quantization_config=quantization_config,
+)
+```
+
+### 이상치 임곗값[[outlier-threshold]]
+
+"이상치"는 특정 임곗값을 초과하는 은닉 상태 값을 의미하며, 이러한 값은 fp16으로 계산됩니다. 값은 일반적으로 정규 분포 ([-3.5, 3.5])를 따르지만, 대규모 모델의 경우 이 분포는 매우 다를 수 있습니다 ([-60, 6] 또는 [6, 60]). 8비트 양자화는 ~5 정도의 값에서 잘 작동하지만, 그 이상에서는 상당한 성능 저하가 발생합니다. 좋은 기본 임곗값 값은 6이지만, 더 불안정한 모델 (소형 모델 또는 미세 조정)에는 더 낮은 임곗값이 필요할 수 있습니다.
+
+모델에 가장 적합한 임곗값을 찾으려면 [`BitsAndBytesConfig`]에서 `llm_int8_threshold` 매개변수를 실험해보는 것이 좋습니다:
+
+```py
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+model_id = "bigscience/bloom-1b7"
+
+quantization_config = BitsAndBytesConfig(
+ llm_int8_threshold=10,
+)
+
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ model_id,
+ device_map=device_map,
+ quantization_config=quantization_config,
+)
+```
+
+### 모듈 변환 건너뛰기[[skip-module-conversion]]
+
+[Jukebox](model_doc/jukebox)와 같은 일부 모델은 모든 모듈을 8비트로 양자화할 필요가 없으며, 이는 실제로 불안정성을 유발할 수 있습니다. Jukebox의 경우, [`BitsAndBytesConfig`]의 `llm_int8_skip_modules` 매개변수를 사용하여 여러 `lm_head` 모듈을 건너뛰어야 합니다:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+model_id = "bigscience/bloom-1b7"
+
+quantization_config = BitsAndBytesConfig(
+ llm_int8_skip_modules=["lm_head"],
+)
+
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ model_id,
+ device_map="auto",
+ quantization_config=quantization_config,
+)
+```
+
+### 미세 조정[[finetuning]]
+
+[PEFT](https://github.com/huggingface/peft) 라이브러리를 사용하면 [flan-t5-large](https://huggingface.co/google/flan-t5-large) 및 [facebook/opt-6.7b](https://huggingface.co/facebook/opt-6.7b)와 같은 대규모 모델을 8비트 양자화로 미세 조정할 수 있습니다. 훈련 시 `device_map` 매개변수를 전달할 필요가 없으며, 모델을 자동으로 GPU에 가져옵니다. 그러나 원하는 경우 `device_map` 매개변수로 장치 맵을 사용자 정의할 수 있습니다 (`device_map="auto"`는 추론에만 사용해야 합니다).
+
+## 4비트 (QLoRA 알고리즘)[[4-bit-(qlora-algorithm)]]
+
+
+
+이 [노트북](https://colab.research.google.com/drive/1ge2F1QSK8Q7h0hn3YKuBCOAS0bK8E0wf)에서 4비트 양자화를 시도해보고 자세한 내용은 이 [블로그 게시물](https://huggingface.co/blog/4bit-transformers-bitsandbytes)에서 확인하세요.
+
+
+
+이 섹션에서는 계산 데이터 유형 변경, Normal Float 4 (NF4) 데이터 유형 사용, 중첩 양자화 사용과 같은 4비트 모델의 특정 기능 일부를 탐구합니다.
+
+
+### 데이터 유형 계산[[compute-data-type]]
+
+계산 속도를 높이기 위해 [`BitsAndBytesConfig`]에서 `bnb_4bit_compute_dtype` 매개변수를 사용하여 데이터 유형을 float32(기본값)에서 bf16으로 변경할 수 있습니다:
+
+```py
+import torch
+from transformers import BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_4bit=True, bnb_4bit_compute_dtype=torch.bfloat16)
+```
+
+### Normal Float 4 (NF4)[[normal-float-4-(nf4)]]
+
+NF4는 [QLoRA](https://hf.co/papers/2305.14314) 논문에서 소개된 4비트 데이터 유형으로, 정규 분포에서 초기화된 가중치에 적합합니다. 4비트 기반 모델을 훈련할 때 NF4를 사용해야 합니다. 이는 [`BitsAndBytesConfig`]에서 `bnb_4bit_quant_type` 매개변수로 설정할 수 있습니다:
+
+```py
+from transformers import BitsAndBytesConfig
+
+nf4_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_quant_type="nf4",
+)
+
+model_nf4 = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=nf4_config)
+```
+
+추론의 경우, `bnb_4bit_quant_type`은 성능에 큰 영향을 미치지 않습니다. 그러나 모델 가중치와 일관성을 유지하기 위해 `bnb_4bit_compute_dtype` 및 `torch_dtype` 값을 사용해야 합니다.
+
+### 중첩 양자화[[nested-quantization]]
+
+중첩 양자화는 추가적인 성능 손실 없이 추가적인 메모리를 절약할 수 있는 기술입니다. 이 기능은 이미 양자화된 가중치의 2차 양자화를 수행하여 매개변수당 추가로 0.4비트를 절약합니다. 예를 들어, 중첩 양자화를 통해 16GB NVIDIA T4 GPU에서 시퀀스 길이 1024, 배치 크기 1, 그레이디언트 누적 4단계를 사용하여 [Llama-13b](https://huggingface.co/meta-llama/Llama-2-13b) 모델을 미세 조정할 수 있습니다.
+
+```py
+from transformers import BitsAndBytesConfig
+
+double_quant_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_use_double_quant=True,
+)
+
+model_double_quant = AutoModelForCausalLM.from_pretrained("meta-llama/Llama-2-13b", quantization_config=double_quant_config)
+```
+
+## `bitsandbytes` 모델의 비양자화[[dequantizing-`bitsandbytes`-models]]
+양자화된 후에는 모델을 원래의 정밀도로 비양자화할 수 있지만, 이는 모델의 품질이 약간 저하될 수 있습니다. 비양자화된 모델에 맞출 수 있는 충분한 GPU RAM이 있는지 확인하세요.
+
+```python
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig, AutoTokenizer
+
+model_id = "facebook/opt-125m"
+
+model = AutoModelForCausalLM.from_pretrained(model_id, BitsAndBytesConfig(load_in_4bit=True))
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+
+model.dequantize()
+
+text = tokenizer("Hello my name is", return_tensors="pt").to(0)
+
+out = model.generate(**text)
+print(tokenizer.decode(out[0]))
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/quantization/eetq.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/quantization/eetq.md
new file mode 100644
index 0000000000000000000000000000000000000000..ef4f4a2684b9f00dd0bd82e1bb75cdf3639ed550
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/quantization/eetq.md
@@ -0,0 +1,47 @@
+
+
+# EETQ [[eetq]]
+
+[EETQ](https://github.com/NetEase-FuXi/EETQ) 라이브러리는 NVIDIA GPU에 대해 int8 채널별(per-channel) 가중치 전용 양자화(weight-only quantization)을 지원합니다. 고성능 GEMM 및 GEMV 커널은 FasterTransformer 및 TensorRT-LLM에서 가져왔습니다. 교정(calibration) 데이터셋이 필요 없으며, 모델을 사전에 양자화할 필요도 없습니다. 또한, 채널별 양자화(per-channel quantization) 덕분에 정확도 저하가 미미합니다.
+
+[릴리스 페이지](https://github.com/NetEase-FuXi/EETQ/releases)에서 eetq를 설치했는지 확인하세요.
+```
+pip install --no-cache-dir https://github.com/NetEase-FuXi/EETQ/releases/download/v1.0.0/EETQ-1.0.0+cu121+torch2.1.2-cp310-cp310-linux_x86_64.whl
+```
+또는 소스 코드 https://github.com/NetEase-FuXi/EETQ 에서 설치할 수 있습니다. EETQ는 CUDA 기능이 8.9 이하이고 7.0 이상이어야 합니다.
+```
+git clone https://github.com/NetEase-FuXi/EETQ.git
+cd EETQ/
+git submodule update --init --recursive
+pip install .
+```
+
+비양자화 모델은 "from_pretrained"를 통해 양자화할 수 있습니다.
+```py
+from transformers import AutoModelForCausalLM, EetqConfig
+path = "/path/to/model".
+quantization_config = EetqConfig("int8")
+model = AutoModelForCausalLM.from_pretrained(path, device_map="auto", quantization_config=quantization_config)
+```
+
+양자화된 모델은 "save_pretrained"를 통해 저장할 수 있으며, "from_pretrained"를 통해 다시 사용할 수 있습니다.
+
+```py
+quant_path = "/path/to/save/quantized/model"
+model.save_pretrained(quant_path)
+model = AutoModelForCausalLM.from_pretrained(quant_path, device_map="auto")
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/quantization/gptq.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/quantization/gptq.md
new file mode 100644
index 0000000000000000000000000000000000000000..c54f09c94a33036400b8992bab8fb34fb2a657c5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/quantization/gptq.md
@@ -0,0 +1,120 @@
+
+
+# GPTQ [[gptq]]
+
+
+
+PEFT를 활용한 GPTQ 양자화를 사용해보시려면 이 [노트북](https://colab.research.google.com/drive/1_TIrmuKOFhuRRiTWN94iLKUFu6ZX4ceb)을 참고하시고, 자세한 내용은 이 [블로그 게시물](https://huggingface.co/blog/gptq-integration)에서 확인하세요!
+
+
+
+[AutoGPTQ](https://github.com/PanQiWei/AutoGPTQ) 라이브러리는 GPTQ 알고리즘을 구현합니다. 이는 훈련 후 양자화 기법으로, 가중치 행렬의 각 행을 독립적으로 양자화하여 오차를 최소화하는 가중치 버전을 찾습니다. 이 가중치는 int4로 양자화되지만, 추론 중에는 실시간으로 fp16으로 복원됩니다. 이는 int4 가중치가 GPU의 전역 메모리 대신 결합된 커널에서 역양자화되기 때문에 메모리 사용량을 4배 절약할 수 있으며, 더 낮은 비트 너비를 사용함으로써 통신 시간이 줄어들어 추론 속도가 빨라질 것으로 기대할 수 있습니다.
+
+시작하기 전에 다음 라이브러리들이 설치되어 있는지 확인하세요:
+
+```bash
+pip install auto-gptq
+pip install --upgrade accelerate optimum transformers
+```
+
+모델을 양자화하려면(현재 텍스트 모델만 지원됨) [`GPTQConfig`] 클래스를 생성하고 양자화할 비트 수, 양자화를 위한 가중치 교정 데이터셋, 그리고 데이터셋을 준비하기 위한 토크나이저를 설정해야 합니다.
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, GPTQConfig
+
+model_id = "facebook/opt-125m"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+gptq_config = GPTQConfig(bits=4, dataset="c4", tokenizer=tokenizer)
+```
+
+자신의 데이터셋을 문자열 리스트 형태로 전달할 수도 있지만, GPTQ 논문에서 사용한 동일한 데이터셋을 사용하는 것을 강력히 권장합니다.
+
+```py
+dataset = ["auto-gptq is an easy-to-use model quantization library with user-friendly apis, based on GPTQ algorithm."]
+gptq_config = GPTQConfig(bits=4, dataset=dataset, tokenizer=tokenizer)
+```
+
+양자화할 모델을 로드하고 `gptq_config`을 [`~AutoModelForCausalLM.from_pretrained`] 메소드에 전달하세요. 모델을 메모리에 맞추기 위해 `device_map="auto"`를 설정하여 모델을 자동으로 CPU로 오프로드하고, 양자화를 위해 모델 모듈이 CPU와 GPU 간에 이동할 수 있도록 합니다.
+
+```py
+quantized_model = AutoModelForCausalLM.from_pretrained(model_id, device_map="auto", quantization_config=gptq_config)
+```
+
+데이터셋이 너무 커서 메모리가 부족한 경우를 대비한 디스크 오프로드는 현재 지원하지 않고 있습니다. 이럴 때는 `max_memory` 매개변수를 사용하여 디바이스(GPU 및 CPU)에서 사용할 메모리 양을 할당해 보세요:
+
+```py
+quantized_model = AutoModelForCausalLM.from_pretrained(model_id, device_map="auto", max_memory={0: "30GiB", 1: "46GiB", "cpu": "30GiB"}, quantization_config=gptq_config)
+```
+
+
+
+하드웨어와 모델 매개변수량에 따라 모델을 처음부터 양자화하는 데 드는 시간이 서로 다를 수 있습니다. 예를 들어, 무료 등급의 Google Colab GPU로 비교적 가벼운 [facebook/opt-350m](https://huggingface.co/facebook/opt-350m) 모델을 양자화하는 데 약 5분이 걸리지만, NVIDIA A100으로 175B에 달하는 매개변수를 가진 모델을 양자화하는 데는 약 4시간에 달하는 시간이 걸릴 수 있습니다. 모델을 양자화하기 전에, Hub에서 해당 모델의 GPTQ 양자화 버전이 이미 존재하는지 확인하는 것이 좋습니다.
+
+
+
+모델이 양자화되면, 모델과 토크나이저를 Hub에 푸시하여 쉽게 공유하고 접근할 수 있습니다. [`GPTQConfig`]를 저장하기 위해 [`~PreTrainedModel.push_to_hub`] 메소드를 사용하세요:
+
+```py
+quantized_model.push_to_hub("opt-125m-gptq")
+tokenizer.push_to_hub("opt-125m-gptq")
+```
+
+양자화된 모델을 로컬에 저장하려면 [`~PreTrainedModel.save_pretrained`] 메소드를 사용할 수 있습니다. 모델이 `device_map` 매개변수로 양자화되었을 경우, 저장하기 전에 전체 모델을 GPU나 CPU로 이동해야 합니다. 예를 들어, 모델을 CPU에 저장하려면 다음과 같이 합니다:
+
+```py
+quantized_model.save_pretrained("opt-125m-gptq")
+tokenizer.save_pretrained("opt-125m-gptq")
+
+# device_map이 설정된 상태에서 양자화된 경우
+quantized_model.to("cpu")
+quantized_model.save_pretrained("opt-125m-gptq")
+```
+
+양자화된 모델을 다시 로드하려면 [`~PreTrainedModel.from_pretrained`] 메소드를 사용하고, `device_map="auto"`를 설정하여 모든 사용 가능한 GPU에 모델을 자동으로 분산시켜 더 많은 메모리를 사용하지 않으면서 모델을 더 빠르게 로드할 수 있습니다.
+
+```py
+from transformers import AutoModelForCausalLM
+
+model = AutoModelForCausalLM.from_pretrained("{your_username}/opt-125m-gptq", device_map="auto")
+```
+
+## ExLlama [[exllama]]
+
+[ExLlama](https://github.com/turboderp/exllama)은 [Llama](model_doc/llama) 모델의 Python/C++/CUDA 구현체로, 4비트 GPTQ 가중치를 사용하여 더 빠른 추론을 위해 설계되었습니다(이 [벤치마크](https://github.com/huggingface/optimum/tree/main/tests/benchmark#gptq-benchmark)를 참고하세요). ['GPTQConfig'] 객체를 생성할 때 ExLlama 커널이 기본적으로 활성화됩니다. 추론 속도를 더욱 높이기 위해, `exllama_config` 매개변수를 구성하여 [ExLlamaV2](https://github.com/turboderp/exllamav2) 커널을 사용할 수 있습니다:
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, GPTQConfig
+
+gptq_config = GPTQConfig(bits=4, exllama_config={"version":2})
+model = AutoModelForCausalLM.from_pretrained("{your_username}/opt-125m-gptq", device_map="auto", quantization_config=gptq_config)
+```
+
+
+
+4비트 모델만 지원되며, 양자화된 모델을 PEFT로 미세 조정하는 경우 ExLlama 커널을 비활성화할 것을 권장합니다.
+
+
+
+ExLlama 커널은 전체 모델이 GPU에 있을 때만 지원됩니다. AutoGPTQ(버전 0.4.2 이상)로 CPU에서 추론을 수행하는 경우 ExLlama 커널을 비활성화해야 합니다. 이를 위해 config.json 파일의 양자화 설정에서 ExLlama 커널과 관련된 속성을 덮어써야 합니다.
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, GPTQConfig
+gptq_config = GPTQConfig(bits=4, use_exllama=False)
+model = AutoModelForCausalLM.from_pretrained("{your_username}/opt-125m-gptq", device_map="cpu", quantization_config=gptq_config)
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/quantization/quanto.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/quantization/quanto.md
new file mode 100644
index 0000000000000000000000000000000000000000..7eff695051d6b8d14fed33672f337ace703d0c71
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/quantization/quanto.md
@@ -0,0 +1,67 @@
+
+
+# Quanto[[quanto]]
+
+
+
+이 [노트북](https://colab.research.google.com/drive/16CXfVmtdQvciSh9BopZUDYcmXCDpvgrT?usp=sharing)으로 Quanto와 transformers를 사용해 보세요!
+
+
+
+
+[🤗 Quanto](https://github.com/huggingface/optimum-quanto) 라이브러리는 다목적 파이토치 양자화 툴킷입니다. 이 라이브러리에서 사용되는 양자화 방법은 선형 양자화입니다. Quanto는 다음과 같은 여러 가지 기능을 제공합니다:
+
+- 가중치 양자화 (`float8`,`int8`,`int4`,`int2`)
+- 활성화 양자화 (`float8`,`int8`)
+- 모달리티에 구애받지 않음 (e.g CV,LLM)
+- 장치에 구애받지 않음 (e.g CUDA,MPS,CPU)
+- `torch.compile` 호환성
+- 특정 장치에 대한 사용자 정의 커널의 쉬운 추가
+- QAT(양자화를 고려한 학습) 지원
+
+
+시작하기 전에 다음 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install quanto accelerate transformers
+```
+
+이제 [`~PreTrainedModel.from_pretrained`] 메소드에 [`QuantoConfig`] 객체를 전달하여 모델을 양자화할 수 있습니다. 이 방식은 `torch.nn.Linear` 레이어를 포함하는 모든 모달리티의 모든 모델에서 잘 작동합니다.
+
+허깅페이스의 transformers 라이브러리는 개발자 편의를 위해 quanto의 인터페이스를 일부 통합하여 지원하고 있으며, 이 방식으로는 가중치 양자화만 지원합니다. 활성화 양자화, 캘리브레이션, QAT 같은 더 복잡한 기능을 수행하기 위해서는 [quanto](https://github.com/huggingface/optimum-quanto) 라이브러리의 해당 함수를 직접 호출해야 합니다.
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, QuantoConfig
+
+model_id = "facebook/opt-125m"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+quantization_config = QuantoConfig(weights="int8")
+quantized_model = AutoModelForCausalLM.from_pretrained(model_id, device_map="cuda:0", quantization_config=quantization_config)
+```
+
+참고로, transformers에서는 아직 직렬화가 지원되지 않지만 곧 지원될 예정입니다!
+모델을 저장하고 싶으면 quanto 라이브러리를 대신 사용할 수 있습니다.
+
+Quanto 라이브러리는 양자화를 위해 선형 양자화 알고리즘을 사용합니다. 비록 기본적인 양자화 기술이지만, 좋은 결과를 얻는데 아주 큰 도움이 됩니다! 바로 아래에 있는 벤치마크(llama-2-7b의 펄플렉서티 지표)를 확인해 보세요. 더 많은 벤치마크는 [여기](https://github.com/huggingface/quanto/tree/main/bench/generation) 에서 찾을 수 있습니다.
+
+
+
+
+
+
+
+
+```bash
+pip install torch
+```
+
+
+
+```bash
+pip install tensorflow
+```
+
+
+
+## 파이프라인 [[pipeline]]
+
+
+
+사용 가능한 작업의 전체 목록은 [Pipelines API 참조](./main_classes/pipelines)를 확인하세요.
+
+
+
+| **태스크** | **설명** | **모달리티** | **파이프라인 ID** |
+|-----------------|----------------------------------------------------------------------|------------------|-----------------------------------------------|
+| 텍스트 분류 | 텍스트에 알맞은 레이블 붙이기 | 자연어 처리(NLP) | pipeline(task="sentiment-analysis") |
+| 텍스트 생성 | 주어진 문자열 입력과 이어지는 텍스트 생성하기 | 자연어 처리(NLP) | pipeline(task="text-generation") |
+| 개체명 인식 | 문자열의 각 토큰마다 알맞은 레이블 붙이기 (인물, 조직, 장소 등등) | 자연어 처리(NLP) | pipeline(task="ner") |
+| 질의응답 | 주어진 문맥과 질문에 따라 올바른 대답하기 | 자연어 처리(NLP) | pipeline(task="question-answering") |
+| 빈칸 채우기 | 문자열의 빈칸에 알맞은 토큰 맞추기 | 자연어 처리(NLP) | pipeline(task="fill-mask") |
+| 요약 | 텍스트나 문서를 요약하기 | 자연어 처리(NLP) | pipeline(task="summarization") |
+| 번역 | 텍스트를 한 언어에서 다른 언어로 번역하기 | 자연어 처리(NLP) | pipeline(task="translation") |
+| 이미지 분류 | 이미지에 알맞은 레이블 붙이기 | 컴퓨터 비전(CV) | pipeline(task="image-classification") |
+| 이미지 분할 | 이미지의 픽셀마다 레이블 붙이기(시맨틱, 파놉틱 및 인스턴스 분할 포함) | 컴퓨터 비전(CV) | pipeline(task="image-segmentation") |
+| 객체 탐지 | 이미지 속 객체의 경계 상자를 그리고 클래스를 예측하기 | 컴퓨터 비전(CV) | pipeline(task="object-detection") |
+| 오디오 분류 | 오디오 파일에 알맞은 레이블 붙이기 | 오디오 | pipeline(task="audio-classification") |
+| 자동 음성 인식 | 오디오 파일 속 음성을 텍스트로 바꾸기 | 오디오 | pipeline(task="automatic-speech-recognition") |
+| 시각 질의응답 | 주어진 이미지와 질문에 대해 올바르게 대답하기 | 멀티모달 | pipeline(task="vqa") |
+| 문서 질의응답 | 주어진 문서와 질문에 대해 올바르게 대답하기 | 멀티모달 | pipeline(task="document-question-answering") |
+| 이미지 캡션 달기 | 주어진 이미지의 캡션 생성하기 | 멀티모달 | pipeline(task="image-to-text") |
+
+먼저 [`pipeline`]의 인스턴스를 생성하고 사용할 작업을 지정합니다. 이 가이드에서는 감정 분석을 위해 [`pipeline`]을 사용하는 예제를 보여드리겠습니다:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("sentiment-analysis")
+```
+
+[`pipeline`]은 감정 분석을 위한 [사전 훈련된 모델](https://huggingface.co/distilbert/distilbert-base-uncased-finetuned-sst-2-english)과 토크나이저를 자동으로 다운로드하고 캐시합니다. 이제 `classifier`를 대상 텍스트에 사용할 수 있습니다:
+
+```py
+>>> classifier("We are very happy to show you the 🤗 Transformers library.")
+[{'label': 'POSITIVE', 'score': 0.9998}]
+```
+
+만약 입력이 여러 개 있는 경우, 입력을 리스트로 [`pipeline`]에 전달하여, 사전 훈련된 모델의 출력을 딕셔너리로 이루어진 리스트 형태로 받을 수 있습니다:
+
+```py
+>>> results = classifier(["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."])
+>>> for result in results:
+... print(f"label: {result['label']}, with score: {round(result['score'], 4)}")
+label: POSITIVE, with score: 0.9998
+label: NEGATIVE, with score: 0.5309
+```
+
+[`pipeline`]은 주어진 과업에 관계없이 데이터셋 전부를 순회할 수도 있습니다. 이 예제에서는 자동 음성 인식을 과업으로 선택해 보겠습니다:
+
+```py
+>>> import torch
+>>> from transformers import pipeline
+
+>>> speech_recognizer = pipeline("automatic-speech-recognition", model="facebook/wav2vec2-base-960h")
+```
+
+데이터셋을 로드할 차례입니다. (자세한 내용은 🤗 Datasets [시작하기](https://huggingface.co/docs/datasets/quickstart#audio)을 참조하세요) 여기에서는 [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) 데이터셋을 로드하겠습니다:
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train") # doctest: +IGNORE_RESULT
+```
+
+데이터셋의 샘플링 레이트가 기존 모델인 [`facebook/wav2vec2-base-960h`](https://huggingface.co/facebook/wav2vec2-base-960h)의 훈련 당시 샘플링 레이트와 일치하는지 확인해야 합니다:
+
+```py
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=speech_recognizer.feature_extractor.sampling_rate))
+```
+
+`"audio"` 열을 호출하면 자동으로 오디오 파일을 가져와서 리샘플링합니다. 첫 4개 샘플에서 원시 웨이브폼 배열을 추출하고 파이프라인에 리스트로 전달하세요:
+
+```py
+>>> result = speech_recognizer(dataset[:4]["audio"])
+>>> print([d["text"] for d in result])
+['I WOULD LIKE TO SET UP A JOINT ACCOUNT WITH MY PARTNER HOW DO I PROCEED WITH DOING THAT', "FONDERING HOW I'D SET UP A JOIN TO HELL T WITH MY WIFE AND WHERE THE AP MIGHT BE", "I I'D LIKE TOY SET UP A JOINT ACCOUNT WITH MY PARTNER I'M NOT SEEING THE OPTION TO DO IT ON THE APSO I CALLED IN TO GET SOME HELP CAN I JUST DO IT OVER THE PHONE WITH YOU AND GIVE YOU THE INFORMATION OR SHOULD I DO IT IN THE AP AN I'M MISSING SOMETHING UQUETTE HAD PREFERRED TO JUST DO IT OVER THE PHONE OF POSSIBLE THINGS", 'HOW DO I FURN A JOINA COUT']
+```
+
+음성이나 비전과 같이 입력이 큰 대규모 데이터셋의 경우, 모든 입력을 메모리에 로드하려면 리스트 대신 제너레이터 형태로 전달해야 합니다. 자세한 내용은 [Pipelines API 참조](./main_classes/pipelines)를 확인하세요.
+
+### 파이프라인에서 다른 모델과 토크나이저 사용하기 [[use-another-model-and-tokenizer-in-the-pipeline]]
+
+[`pipeline`]은 [Hub](https://huggingface.co/models)의 모든 모델을 사용할 수 있기 때문에, [`pipeline`]을 다른 용도에 맞게 쉽게 수정할 수 있습니다. 예를 들어, 프랑스어 텍스트를 처리할 수 있는 모델을 사용하기 위해선 Hub의 태그를 사용하여 적절한 모델을 필터링하면 됩니다. 필터링된 결과의 상위 항목으로는 프랑스어 텍스트에 사용할 수 있는 다국어 [BERT 모델](https://huggingface.co/nlptown/bert-base-multilingual-uncased-sentiment)이 반환됩니다:
+
+```py
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+```
+
+
+
+[`AutoModelForSequenceClassification`]과 [`AutoTokenizer`]를 사용하여 사전 훈련된 모델과 관련된 토크나이저를 로드하세요 (다음 섹션에서 [`AutoClass`]에 대해 더 자세히 알아보겠습니다):
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+[`TFAutoModelForSequenceClassification`]과 [`AutoTokenizer`]를 사용하여 사전 훈련된 모델과 관련된 토크나이저를 로드하세요 (다음 섹션에서 [`TFAutoClass`]에 대해 더 자세히 알아보겠습니다):
+
+```py
+>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+
+[`pipeline`]에서 모델과 토크나이저를 지정하면, 이제 `classifier`를 프랑스어 텍스트에 적용할 수 있습니다:
+
+```py
+>>> classifier = pipeline("sentiment-analysis", model=model, tokenizer=tokenizer)
+>>> classifier("Nous sommes très heureux de vous présenter la bibliothèque 🤗 Transformers.")
+[{'label': '5 stars', 'score': 0.7273}]
+```
+
+마땅한 모델을 찾을 수 없는 경우 데이터를 기반으로 사전 훈련된 모델을 미세조정해야 합니다. 미세조정 방법에 대한 자세한 내용은 [미세조정 튜토리얼](./training)을 참조하세요. 사전 훈련된 모델을 미세조정한 후에는 모델을 Hub의 커뮤니티와 공유하여 머신러닝 민주화에 기여해주세요! 🤗
+
+## AutoClass [[autoclass]]
+
+
+
+
+```py
+>>> pt_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="pt",
+... )
+```
+
+
+
+```py
+>>> tf_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="tf",
+... )
+```
+
+
+
+
+
+[전처리](./preprocessing) 튜토리얼을 참조하시면 토큰화에 대한 자세한 설명과 함께 이미지, 오디오와 멀티모달 입력을 전처리하기 위한 [`AutoImageProcessor`]와 [`AutoFeatureExtractor`], [`AutoProcessor`]의 사용방법도 알 수 있습니다.
+
+
+
+### AutoModel [[automodel]]
+
+
+
+🤗 Transformers는 사전 훈련된 인스턴스를 간단하고 통합된 방법으로 로드할 수 있습니다. 즉, [`AutoTokenizer`]처럼 [`AutoModel`]을 로드할 수 있습니다. 유일한 차이점은 과업에 알맞은 [`AutoModel`]을 선택해야 한다는 점입니다. 텍스트 (또는 시퀀스) 분류의 경우 [`AutoModelForSequenceClassification`]을 로드해야 합니다:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+[`AutoModel`] 클래스에서 지원하는 과업에 대해서는 [과업 요약](./task_summary)을 참조하세요.
+
+
+
+이제 전처리된 입력 묶음을 직접 모델에 전달해야 합니다. 아래처럼 `**`를 앞에 붙여 딕셔너리를 풀어주면 됩니다:
+
+```py
+>>> pt_outputs = pt_model(**pt_batch)
+```
+
+모델의 최종 활성화 함수 출력은 `logits` 속성에 담겨있습니다. `logits`에 softmax 함수를 적용하여 확률을 얻을 수 있습니다:
+
+```py
+>>> from torch import nn
+
+>>> pt_predictions = nn.functional.softmax(pt_outputs.logits, dim=-1)
+>>> print(pt_predictions)
+tensor([[0.0021, 0.0018, 0.0115, 0.2121, 0.7725],
+ [0.2084, 0.1826, 0.1969, 0.1755, 0.2365]], grad_fn=)
+```
+
+
+🤗 Transformers는 사전 훈련된 인스턴스를 간단하고 통합된 방법으로 로드할 수 있습니다. 즉, [`AutoTokenizer`]처럼 [`TFAutoModel`]을 로드할 수 있습니다. 유일한 차이점은 과업에 알맞은 [`TFAutoModel`]을 선택해야 한다는 점입니다. 텍스트 (또는 시퀀스) 분류의 경우 [`TFAutoModelForSequenceClassification`]을 로드해야 합니다:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+[`AutoModel`] 클래스에서 지원하는 과업에 대해서는 [과업 요약](./task_summary)을 참조하세요.
+
+
+
+이제 전처리된 입력 묶음을 직접 모델에 전달해야 합니다. 아래처럼 그대로 텐서를 전달하면 됩니다:
+
+```py
+>>> tf_outputs = tf_model(tf_batch)
+```
+
+모델의 최종 활성화 함수 출력은 `logits` 속성에 담겨있습니다. `logits`에 softmax 함수를 적용하여 확률을 얻을 수 있습니다:
+
+```py
+>>> import tensorflow as tf
+
+>>> tf_predictions = tf.nn.softmax(tf_outputs.logits, axis=-1)
+>>> tf_predictions # doctest: +IGNORE_RESULT
+```
+
+
+
+
+
+모든 🤗 Transformers 모델(PyTorch 또는 TensorFlow)은 (softmax와 같은) 최종 활성화 함수 *이전에* 텐서를 출력합니다. 왜냐하면 최종 활성화 함수의 출력은 종종 손실 함수 출력과 결합되기 때문입니다. 모델 출력은 특수한 데이터 클래스이므로 IDE에서 자동 완성됩니다. 모델 출력은 튜플이나 딕셔너리처럼 동작하며 (정수, 슬라이스 또는 문자열로 인덱싱 가능), None인 속성은 무시됩니다.
+
+
+
+### 모델 저장하기 [[save-a-model]]
+
+
+
+미세조정된 모델을 토크나이저와 함께 저장하려면 [`PreTrainedModel.save_pretrained`]를 사용하세요:
+
+```py
+>>> pt_save_directory = "./pt_save_pretrained"
+>>> tokenizer.save_pretrained(pt_save_directory) # doctest: +IGNORE_RESULT
+>>> pt_model.save_pretrained(pt_save_directory)
+```
+
+모델을 다시 사용하려면 [`PreTrainedModel.from_pretrained`]로 모델을 다시 로드하세요:
+
+```py
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained("./pt_save_pretrained")
+```
+
+
+미세조정된 모델을 토크나이저와 함께 저장하려면 [`TFPreTrainedModel.save_pretrained`]를 사용하세요:
+
+```py
+>>> tf_save_directory = "./tf_save_pretrained"
+>>> tokenizer.save_pretrained(tf_save_directory) # doctest: +IGNORE_RESULT
+>>> tf_model.save_pretrained(tf_save_directory)
+```
+
+모델을 다시 사용하려면 [`TFPreTrainedModel.from_pretrained`]로 모델을 다시 로드하세요:
+
+```py
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("./tf_save_pretrained")
+```
+
+
+
+🤗 Transformers의 멋진 기능 중 하나는 모델을 PyTorch 또는 TensorFlow 모델로 저장해뒀다가 다른 프레임워크로 다시 로드할 수 있는 점입니다. `from_pt` 또는 `from_tf` 매개변수를 사용하여 모델을 한 프레임워크에서 다른 프레임워크로 변환할 수 있습니다:
+
+
+
+
+```py
+>>> from transformers import AutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(pt_save_directory)
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(pt_save_directory, from_pt=True)
+```
+
+
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(tf_save_directory)
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(tf_save_directory, from_tf=True)
+```
+
+
+
+## 커스텀 모델 구축하기 [[custom-model-builds]]
+
+모델의 구성 클래스를 수정하여 모델의 구조를 바꿀 수 있습니다. (은닉층이나 어텐션 헤드의 수와 같은) 모델의 속성은 구성에서 지정되기 때문입니다. 커스텀 구성 클래스로 모델을 만들면 처음부터 시작해야 합니다. 모델 속성은 무작위로 초기화되므로 의미 있는 결과를 얻으려면 먼저 모델을 훈련시켜야 합니다.
+
+먼저 [`AutoConfig`]를 가져오고 수정하고 싶은 사전학습된 모델을 로드하세요. [`AutoConfig.from_pretrained`] 내부에서 (어텐션 헤드 수와 같이) 변경하려는 속성를 지정할 수 있습니다:
+
+```py
+>>> from transformers import AutoConfig
+
+>>> my_config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased", n_heads=12)
+```
+
+
+
+[`AutoModel.from_config`]를 사용하여 바꾼 구성대로 모델을 생성하세요:
+
+```py
+>>> from transformers import AutoModel
+
+>>> my_model = AutoModel.from_config(my_config)
+```
+
+
+[`TFAutoModel.from_config`]를 사용하여 바꾼 구성대로 모델을 생성하세요:
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> my_model = TFAutoModel.from_config(my_config)
+```
+
+
+
+커스텀 구성에 대한 자세한 내용은 [커스텀 아키텍처 만들기](./create_a_model) 가이드를 확인하세요.
+
+## Trainer - PyTorch에 최적화된 훈련 루프 [[trainer-a-pytorch-optimized-training-loop]]
+
+모든 모델은 [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module)이므로 일반적인 훈련 루프에서 사용할 수 있습니다. 직접 훈련 루프를 작성할 수도 있지만, 🤗 Transformers는 PyTorch를 위한 [`Trainer`] 클래스를 제공합니다. 이 클래스에는 기본 훈련 루프가 포함되어 있으며 분산 훈련, 혼합 정밀도 등과 같은 기능을 추가로 제공합니다.
+
+과업에 따라 다르지만 일반적으로 [`Trainer`]에 다음 매개변수를 전달합니다:
+
+1. [`PreTrainedModel`] 또는 [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module)로 시작합니다:
+
+ ```py
+ >>> from transformers import AutoModelForSequenceClassification
+
+ >>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+2. [`TrainingArguments`]는 학습률, 배치 크기, 훈련할 에포크 수와 같은 모델 하이퍼파라미터를 포함합니다. 훈련 인자를 지정하지 않으면 기본값이 사용됩니다:
+
+ ```py
+ >>> from transformers import TrainingArguments
+
+ >>> training_args = TrainingArguments(
+ ... output_dir="path/to/save/folder/",
+ ... learning_rate=2e-5,
+ ... per_device_train_batch_size=8,
+ ... per_device_eval_batch_size=8,
+ ... num_train_epochs=2,
+ ... )
+ ```
+
+3. 토크나이저, 이미지 프로세서, 특징 추출기(feature extractor) 또는 프로세서와 전처리 클래스를 로드하세요:
+
+ ```py
+ >>> from transformers import AutoTokenizer
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+4. 데이터셋을 로드하세요:
+
+ ```py
+ >>> from datasets import load_dataset
+
+ >>> dataset = load_dataset("rotten_tomatoes") # doctest: +IGNORE_RESULT
+ ```
+
+5. 데이터셋을 토큰화하는 함수를 생성하세요:
+
+ ```py
+ >>> def tokenize_dataset(dataset):
+ ... return tokenizer(dataset["text"])
+ ```
+
+ 그리고 [`~datasets.Dataset.map`]로 데이터셋 전체에 적용하세요:
+
+ ```py
+ >>> dataset = dataset.map(tokenize_dataset, batched=True)
+ ```
+
+6. [`DataCollatorWithPadding`]을 사용하여 데이터셋의 표본 묶음을 만드세요:
+
+ ```py
+ >>> from transformers import DataCollatorWithPadding
+
+ >>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
+ ```
+
+이제 위의 모든 클래스를 [`Trainer`]로 모으세요:
+
+```py
+>>> from transformers import Trainer
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=dataset["train"],
+... eval_dataset=dataset["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... ) # doctest: +SKIP
+```
+
+준비가 되었으면 [`~Trainer.train`]을 호출하여 훈련을 시작하세요:
+
+```py
+>>> trainer.train() # doctest: +SKIP
+```
+
+
+
+번역이나 요약과 같이 시퀀스-시퀀스 모델을 사용하는 과업에는 [`Seq2SeqTrainer`] 및 [`Seq2SeqTrainingArguments`] 클래스를 사용하세요.
+
+
+
+[`Trainer`] 내의 메서드를 서브클래스화하여 훈련 루프를 바꿀 수도 있습니다. 이러면 손실 함수, 옵티마이저, 스케줄러와 같은 기능 또한 바꿀 수 있게 됩니다. 변경 가능한 메소드에 대해서는 [`Trainer`] 문서를 참고하세요.
+
+훈련 루프를 수정하는 다른 방법은 [Callbacks](./main_classes/callback)를 사용하는 것입니다. Callbacks로 다른 라이브러리와 통합하고, 훈련 루프를 체크하여 진행 상황을 보고받거나, 훈련을 조기에 중단할 수 있습니다. Callbacks은 훈련 루프 자체를 바꾸지는 않습니다. 손실 함수와 같은 것을 바꾸려면 [`Trainer`]를 서브클래스화해야 합니다.
+
+## TensorFlow로 훈련시키기 [[train-with-tensorflow]]
+
+모든 모델은 [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model)이므로 [Keras](https://keras.io/) API를 통해 TensorFlow에서 훈련시킬 수 있습니다. 🤗 Transformers는 데이터셋을 쉽게 `tf.data.Dataset` 형태로 쉽게 로드할 수 있는 [`~TFPreTrainedModel.prepare_tf_dataset`] 메소드를 제공하기 때문에, Keras의 [`compile`](https://keras.io/api/models/model_training_apis/#compile-method) 및 [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) 메소드로 바로 훈련을 시작할 수 있습니다.
+
+1. [`TFPreTrainedModel`] 또는 [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model)로 시작합니다:
+
+ ```py
+ >>> from transformers import TFAutoModelForSequenceClassification
+
+ >>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+2. 토크나이저, 이미지 프로세서, 특징 추출기(feature extractor) 또는 프로세서와 같은 전처리 클래스를 로드하세요:
+
+ ```py
+ >>> from transformers import AutoTokenizer
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+3. 데이터셋을 토큰화하는 함수를 생성하세요:
+
+ ```py
+ >>> def tokenize_dataset(dataset):
+ ... return tokenizer(dataset["text"]) # doctest: +SKIP
+ ```
+
+4. [`~datasets.Dataset.map`]을 사용하여 전체 데이터셋에 토큰화 함수를 적용하고, 데이터셋과 토크나이저를 [`~TFPreTrainedModel.prepare_tf_dataset`]에 전달하세요. 배치 크기를 변경하거나 데이터셋을 섞을 수도 있습니다:
+
+ ```py
+ >>> dataset = dataset.map(tokenize_dataset) # doctest: +SKIP
+ >>> tf_dataset = model.prepare_tf_dataset(
+ ... dataset["train"], batch_size=16, shuffle=True, tokenizer=tokenizer
+ ... ) # doctest: +SKIP
+ ```
+
+5. 준비되었으면 `compile` 및 `fit`를 호출하여 훈련을 시작하세요. 🤗 Transformers의 모든 모델은 과업과 관련된 기본 손실 함수를 가지고 있으므로 명시적으로 지정하지 않아도 됩니다:
+
+ ```py
+ >>> from tensorflow.keras.optimizers import Adam
+
+ >>> model.compile(optimizer=Adam(3e-5)) # No loss argument!
+ >>> model.fit(tf_dataset) # doctest: +SKIP
+ ```
+
+## 다음 단계는 무엇인가요? [[whats-next]]
+
+🤗 Transformers 둘러보기를 모두 읽으셨다면, 가이드를 살펴보고 더 구체적인 것을 수행하는 방법을 알아보세요. 이를테면 커스텀 모델 구축하는 방법, 과업에 알맞게 모델을 미세조정하는 방법, 스크립트로 모델 훈련하는 방법 등이 있습니다. 🤗 Transformers 핵심 개념에 대해 더 알아보려면 커피 한 잔 들고 개념 가이드를 살펴보세요!
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/run_scripts.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/run_scripts.md
new file mode 100644
index 0000000000000000000000000000000000000000..715a949dde4280e7abca29cd55a7717c70df6088
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/run_scripts.md
@@ -0,0 +1,375 @@
+
+
+# 스크립트로 실행하기[[train-with-a-script]]
+
+🤗 Transformers 노트북과 함께 [PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch), [TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow), 또는 [JAX/Flax](https://github.com/huggingface/transformers/tree/main/examples/flax)를 사용해 특정 태스크에 대한 모델을 훈련하는 방법을 보여주는 예제 스크립트도 있습니다.
+
+또한 [연구 프로젝트](https://github.com/huggingface/transformers/tree/main/examples/research_projects) 및 [레거시 예제](https://github.com/huggingface/transformers/tree/main/examples/legacy)에서 대부분 커뮤니티에서 제공한 스크립트를 찾을 수 있습니다.
+이러한 스크립트는 적극적으로 유지 관리되지 않으며 최신 버전의 라이브러리와 호환되지 않을 가능성이 높은 특정 버전의 🤗 Transformers를 필요로 합니다.
+
+예제 스크립트가 모든 문제에서 바로 작동하는 것은 아니며, 해결하려는 문제에 맞게 스크립트를 변경해야 할 수도 있습니다.
+이를 위해 대부분의 스크립트에는 데이터 전처리 방법이 나와있어 필요에 따라 수정할 수 있습니다.
+
+예제 스크립트에 구현하고 싶은 기능이 있으면 pull request를 제출하기 전에 [포럼](https://discuss.huggingface.co/) 또는 [이슈](https://github.com/huggingface/transformers/issues)에서 논의해 주세요.
+버그 수정은 환영하지만 가독성을 희생하면서까지 더 많은 기능을 추가하는 pull request는 병합(merge)하지 않을 가능성이 높습니다.
+
+이 가이드에서는 [PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization) 및 [TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/summarization)에서 요약 훈련하는
+ 스크립트 예제를 실행하는 방법을 설명합니다.
+특별한 설명이 없는 한 모든 예제는 두 프레임워크 모두에서 작동할 것으로 예상됩니다.
+
+## 설정하기[[setup]]
+
+최신 버전의 예제 스크립트를 성공적으로 실행하려면 새 가상 환경에서 **소스로부터 🤗 Transformers를 설치**해야 합니다:
+
+```bash
+git clone https://github.com/huggingface/transformers
+cd transformers
+pip install .
+```
+
+이전 버전의 예제 스크립트를 보려면 아래 토글을 클릭하세요:
+
+
+ 이전 버전의 🤗 Transformers 예제
+
+
+
+그리고 다음과 같이 복제(clone)해온 🤗 Transformers 버전을 특정 버전(예: v3.5.1)으로 전환하세요:
+
+```bash
+git checkout tags/v3.5.1
+```
+
+올바른 라이브러리 버전을 설정한 후 원하는 예제 폴더로 이동하여 예제별로 라이브러리에 대한 요구 사항(requirements)을 설치합니다:
+
+```bash
+pip install -r requirements.txt
+```
+
+## 스크립트 실행하기[[run-a-script]]
+
+
+
+예제 스크립트는 🤗 [Datasets](https://huggingface.co/docs/datasets/) 라이브러리에서 데이터 세트를 다운로드하고 전처리합니다.
+그런 다음 스크립트는 요약 기능을 지원하는 아키텍처에서 [Trainer](https://huggingface.co/docs/transformers/main_classes/trainer)를 사용하여 데이터 세트를 미세 조정합니다.
+다음 예는 [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail) 데이터 세트에서 [T5-small](https://huggingface.co/google-t5/t5-small)을 미세 조정합니다.
+T5 모델은 훈련 방식에 따라 추가 `source_prefix` 인수가 필요하며, 이 프롬프트는 요약 작업임을 T5에 알려줍니다.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+예제 스크립트는 🤗 [Datasets](https://huggingface.co/docs/datasets/) 라이브러리에서 데이터 세트를 다운로드하고 전처리합니다.
+그런 다음 스크립트는 요약 기능을 지원하는 아키텍처에서 Keras를 사용하여 데이터 세트를 미세 조정합니다.
+다음 예는 [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail) 데이터 세트에서 [T5-small](https://huggingface.co/google-t5/t5-small)을 미세 조정합니다.
+T5 모델은 훈련 방식에 따라 추가 `source_prefix` 인수가 필요하며, 이 프롬프트는 요약 작업임을 T5에 알려줍니다.
+```bash
+python examples/tensorflow/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## 혼합 정밀도(mixed precision)로 분산 훈련하기[[distributed-training-and-mixed-precision]]
+
+[Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) 클래스는 분산 훈련과 혼합 정밀도(mixed precision)를 지원하므로 스크립트에서도 사용할 수 있습니다.
+이 두 가지 기능을 모두 활성화하려면 다음 두 가지를 설정해야 합니다:
+
+- `fp16` 인수를 추가해 혼합 정밀도(mixed precision)를 활성화합니다.
+- `nproc_per_node` 인수를 추가해 사용할 GPU 개수를 설정합니다.
+
+```bash
+torchrun \
+ --nproc_per_node 8 pytorch/summarization/run_summarization.py \
+ --fp16 \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+TensorFlow 스크립트는 분산 훈련을 위해 [`MirroredStrategy`](https://www.tensorflow.org/guide/distributed_training#mirroredstrategy)를 활용하며, 훈련 스크립트에 인수를 추가할 필요가 없습니다.
+다중 GPU 환경이라면, TensorFlow 스크립트는 기본적으로 여러 개의 GPU를 사용합니다.
+
+## TPU 위에서 스크립트 실행하기[[run-a-script-on-a-tpu]]
+
+
+
+Tensor Processing Units (TPUs)는 성능을 가속화하기 위해 특별히 설계되었습니다.
+PyTorch는 [XLA](https://www.tensorflow.org/xla) 딥러닝 컴파일러와 함께 TPU를 지원합니다(자세한 내용은 [여기](https://github.com/pytorch/xla/blob/master/README.md) 참조).
+TPU를 사용하려면 `xla_spawn.py` 스크립트를 실행하고 `num_cores` 인수를 사용하여 사용하려는 TPU 코어 수를 설정합니다.
+
+```bash
+python xla_spawn.py --num_cores 8 \
+ summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+Tensor Processing Units (TPUs)는 성능을 가속화하기 위해 특별히 설계되었습니다.
+TensorFlow 스크립트는 TPU를 훈련에 사용하기 위해 [`TPUStrategy`](https://www.tensorflow.org/guide/distributed_training#tpustrategy)를 활용합니다.
+TPU를 사용하려면 TPU 리소스의 이름을 `tpu` 인수에 전달합니다.
+
+```bash
+python run_summarization.py \
+ --tpu name_of_tpu_resource \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## 🤗 Accelerate로 스크립트 실행하기[[run-a-script-with-accelerate]]
+
+🤗 [Accelerate](https://huggingface.co/docs/accelerate)는 PyTorch 훈련 과정에 대한 완전한 가시성을 유지하면서 여러 유형의 설정(CPU 전용, 다중 GPU, TPU)에서 모델을 훈련할 수 있는 통합 방법을 제공하는 PyTorch 전용 라이브러리입니다.
+🤗 Accelerate가 설치되어 있는지 확인하세요:
+
+> 참고: Accelerate는 빠르게 개발 중이므로 스크립트를 실행하려면 accelerate를 설치해야 합니다.
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+`run_summarization.py` 스크립트 대신 `run_summarization_no_trainer.py` 스크립트를 사용해야 합니다.
+🤗 Accelerate 클래스가 지원되는 스크립트는 폴더에 `task_no_trainer.py` 파일이 있습니다.
+다음 명령을 실행하여 구성 파일을 생성하고 저장합니다:
+```bash
+accelerate config
+```
+
+설정을 테스트하여 올바르게 구성되었는지 확인합니다:
+
+```bash
+accelerate test
+```
+
+이제 훈련을 시작할 준비가 되었습니다:
+
+```bash
+accelerate launch run_summarization_no_trainer.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir ~/tmp/tst-summarization
+```
+
+## 사용자 정의 데이터 세트 사용하기[[use-a-custom-dataset]]
+
+요약 스크립트는 사용자 지정 데이터 세트가 CSV 또는 JSON 파일인 경우 지원합니다.
+사용자 지정 데이터 세트를 사용하는 경우에는 몇 가지 추가 인수를 지정해야 합니다:
+
+- `train_file`과 `validation_file`은 훈련 및 검증 파일의 경로를 지정합니다.
+- `text_column`은 요약할 입력 텍스트입니다.
+- `summary_column`은 출력할 대상 텍스트입니다.
+
+사용자 지정 데이터 세트를 사용하는 요약 스크립트는 다음과 같습니다:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --train_file path_to_csv_or_jsonlines_file \
+ --validation_file path_to_csv_or_jsonlines_file \
+ --text_column text_column_name \
+ --summary_column summary_column_name \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --overwrite_output_dir \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --predict_with_generate
+```
+
+## 스크립트 테스트하기[[test-a-script]]
+
+전체 데이터 세트를 대상으로 훈련을 완료하는데 꽤 오랜 시간이 걸리기 때문에, 작은 데이터 세트에서 모든 것이 예상대로 실행되는지 확인하는 것이 좋습니다.
+
+다음 인수를 사용하여 데이터 세트를 최대 샘플 수로 잘라냅니다:
+- `max_train_samples`
+- `max_eval_samples`
+- `max_predict_samples`
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --max_train_samples 50 \
+ --max_eval_samples 50 \
+ --max_predict_samples 50 \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+모든 예제 스크립트가 `max_predict_samples` 인수를 지원하지는 않습니다.
+스크립트가 이 인수를 지원하는지 확실하지 않은 경우 `-h` 인수를 추가하여 확인하세요:
+
+```bash
+examples/pytorch/summarization/run_summarization.py -h
+```
+
+## 체크포인트(checkpoint)에서 훈련 이어서 하기[[resume-training-from-checkpoint]]
+
+또 다른 유용한 옵션은 이전 체크포인트에서 훈련을 재개하는 것입니다.
+이렇게 하면 훈련이 중단되더라도 처음부터 다시 시작하지 않고 중단한 부분부터 다시 시작할 수 있습니다.
+체크포인트에서 훈련을 재개하는 방법에는 두 가지가 있습니다.
+
+첫 번째는 `output_dir previous_output_dir` 인수를 사용하여 `output_dir`에 저장된 최신 체크포인트부터 훈련을 재개하는 방법입니다.
+이 경우 `overwrite_output_dir`을 제거해야 합니다:
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --output_dir previous_output_dir \
+ --predict_with_generate
+```
+
+두 번째는 `resume_from_checkpoint path_to_specific_checkpoint` 인수를 사용하여 특정 체크포인트 폴더에서 훈련을 재개하는 방법입니다.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --resume_from_checkpoint path_to_specific_checkpoint \
+ --predict_with_generate
+```
+
+## 모델 공유하기[[share-your-model]]
+
+모든 스크립트는 최종 모델을 [Model Hub](https://huggingface.co/models)에 업로드할 수 있습니다.
+시작하기 전에 Hugging Face에 로그인했는지 확인하세요:
+```bash
+huggingface-cli login
+```
+
+그런 다음 스크립트에 `push_to_hub` 인수를 추가합니다.
+이 인수는 Hugging Face 사용자 이름과 `output_dir`에 지정된 폴더 이름으로 저장소를 생성합니다.
+
+저장소에 특정 이름을 지정하려면 `push_to_hub_model_id` 인수를 사용하여 추가합니다.
+저장소는 네임스페이스 아래에 자동으로 나열됩니다.
+다음 예는 특정 저장소 이름으로 모델을 업로드하는 방법입니다:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --push_to_hub \
+ --push_to_hub_model_id finetuned-t5-cnn_dailymail \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/sagemaker.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/sagemaker.md
new file mode 100644
index 0000000000000000000000000000000000000000..18aafc28a1612d3c59cc39d9aeefc628c1ef697d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/sagemaker.md
@@ -0,0 +1,28 @@
+
+
+# Amazon SageMaker에서 학습 실행하기[[run-training-on-amazon-sagemaker]]
+
+문서가 [hf.co/docs/sagemaker](https://huggingface.co/docs/sagemaker)로 이동되었습니다. 이 페이지는 `transformers` 5.0 에서 삭제될 예정입니다.
+
+### 목차[[table-of-content]]
+
+- [Train Hugging Face models on Amazon SageMaker with the SageMaker Python SDK](https://huggingface.co/docs/sagemaker/train)
+- [Deploy Hugging Face models to Amazon SageMaker with the SageMaker Python SDK](https://huggingface.co/docs/sagemaker/inference)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/serialization.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/serialization.md
new file mode 100644
index 0000000000000000000000000000000000000000..2e521e2b7b4af83b4a95df0c3e28f17f957ba411
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/serialization.md
@@ -0,0 +1,181 @@
+
+
+# ONNX로 내보내기 [[export-to-onnx]]
+
+🤗 Transformers 모델을 제품 환경에서 배포하기 위해서는 모델을 직렬화된 형식으로 내보내고 특정 런타임과 하드웨어에서 로드하고 실행할 수 있으면 유용합니다.
+
+🤗 Optimum은 Transformers의 확장으로, PyTorch 또는 TensorFlow에서 모델을 ONNX와 TFLite와 같은 직렬화된 형식으로 내보낼 수 있도록 하는 `exporters` 모듈을 통해 제공됩니다. 🤗 Optimum은 또한 성능 최적화 도구 세트를 제공하여 특정 하드웨어에서 모델을 훈련하고 실행할 때 최대 효율성을 달성할 수 있습니다.
+
+이 안내서는 🤗 Optimum을 사용하여 🤗 Transformers 모델을 ONNX로 내보내는 방법을 보여줍니다. TFLite로 모델을 내보내는 안내서는 [TFLite로 내보내기 페이지](tflite)를 참조하세요.
+
+## ONNX로 내보내기 [[export-to-onnx]]
+
+[ONNX (Open Neural Network eXchange)](http://onnx.ai)는 PyTorch와 TensorFlow를 포함한 다양한 프레임워크에서 심층 학습 모델을 나타내는 데 사용되는 공통 연산자 세트와 공통 파일 형식을 정의하는 오픈 표준입니다. 모델이 ONNX 형식으로 내보내지면 이러한 연산자를 사용하여 신경망을 통해 데이터가 흐르는 흐름을 나타내는 계산 그래프(일반적으로 _중간 표현_이라고 함)가 구성됩니다.
+
+표준화된 연산자와 데이터 유형을 가진 그래프를 노출함으로써, ONNX는 프레임워크 간에 쉽게 전환할 수 있습니다. 예를 들어, PyTorch에서 훈련된 모델을 ONNX 형식으로 내보내고 TensorFlow에서 가져올 수 있습니다(그 반대도 가능합니다).
+
+ONNX 형식으로 내보낸 모델은 다음과 같이 사용할 수 있습니다:
+- [그래프 최적화](https://huggingface.co/docs/optimum/onnxruntime/usage_guides/optimization) 및 [양자화](https://huggingface.co/docs/optimum/onnxruntime/usage_guides/quantization)와 같은 기법을 사용하여 추론을 위해 최적화됩니다.
+- ONNX Runtime을 통해 실행할 수 있습니다. [`ORTModelForXXX` 클래스들](https://huggingface.co/docs/optimum/onnxruntime/package_reference/modeling_ort)을 통해 동일한 `AutoModel` API를 따릅니다. 이 API는 🤗 Transformers에서 사용하는 것과 동일합니다.
+- [최적화된 추론 파이프라인](https://huggingface.co/docs/optimum/main/en/onnxruntime/usage_guides/pipelines)을 사용할 수 있습니다. 이는 🤗 Transformers의 [`pipeline`] 함수와 동일한 API를 가지고 있습니다.
+
+🤗 Optimum은 구성 객체를 활용하여 ONNX 내보내기를 지원합니다. 이러한 구성 객체는 여러 모델 아키텍처에 대해 미리 준비되어 있으며 다른 아키텍처에 쉽게 확장할 수 있도록 설계되었습니다.
+
+미리 준비된 구성 목록은 [🤗 Optimum 문서](https://huggingface.co/docs/optimum/exporters/onnx/overview)를 참조하세요.
+
+🤗 Transformers 모델을 ONNX로 내보내는 두 가지 방법이 있습니다. 여기에서 두 가지 방법을 모두 보여줍니다:
+
+- 🤗 Optimum을 사용하여 CLI로 내보내기
+- `optimum.onnxruntime`을 사용하여 🤗 Optimum으로 ONNX로 내보내기
+
+### CLI를 사용하여 🤗 Transformers 모델을 ONNX로 내보내기 [[exporting-a-transformers-model-to-onnx-with-cli]]
+
+🤗 Transformers 모델을 ONNX로 내보내려면 먼저 추가 종속성을 설치하세요:
+
+```bash
+pip install optimum[exporters]
+```
+
+사용 가능한 모든 인수를 확인하려면 [🤗 Optimum 문서](https://huggingface.co/docs/optimum/exporters/onnx/usage_guides/export_a_model#exporting-a-model-to-onnx-using-the-cli)를 참조하거나 명령줄에서 도움말을 보세요.
+
+```bash
+optimum-cli export onnx --help
+```
+
+예를 들어, 🤗 Hub에서 `distilbert/distilbert-base-uncased-distilled-squad`와 같은 모델의 체크포인트를 내보내려면 다음 명령을 실행하세요:
+
+```bash
+optimum-cli export onnx --model distilbert/distilbert-base-uncased-distilled-squad distilbert_base_uncased_squad_onnx/
+```
+
+위와 같이 진행 상황을 나타내는 로그가 표시되고 결과인 `model.onnx`가 저장된 위치가 표시됩니다.
+
+```bash
+Validating ONNX model distilbert_base_uncased_squad_onnx/model.onnx...
+ -[✓] ONNX model output names match reference model (start_logits, end_logits)
+ - Validating ONNX Model output "start_logits":
+ -[✓] (2, 16) matches (2, 16)
+ -[✓] all values close (atol: 0.0001)
+ - Validating ONNX Model output "end_logits":
+ -[✓] (2, 16) matches (2, 16)
+ -[✓] all values close (atol: 0.0001)
+The ONNX export succeeded and the exported model was saved at: distilbert_base_uncased_squad_onnx
+```
+
+위의 예제는 🤗 Hub에서 체크포인트를 내보내는 것을 설명합니다. 로컬 모델을 내보낼 때에는 모델의 가중치와 토크나이저 파일을 동일한 디렉토리(`local_path`)에 저장했는지 확인하세요. CLI를 사용할 때에는 🤗 Hub의 체크포인트 이름 대신 `model` 인수에 `local_path`를 전달하고 `--task` 인수를 제공하세요. 지원되는 작업의 목록은 [🤗 Optimum 문서](https://huggingface.co/docs/optimum/exporters/task_manager)를 참조하세요. `task` 인수가 제공되지 않으면 작업에 특화된 헤드 없이 모델 아키텍처로 기본 설정됩니다.
+
+```bash
+optimum-cli export onnx --model local_path --task question-answering distilbert_base_uncased_squad_onnx/
+```
+
+그 결과로 생성된 `model.onnx` 파일은 ONNX 표준을 지원하는 많은 [가속기](https://onnx.ai/supported-tools.html#deployModel) 중 하나에서 실행할 수 있습니다. 예를 들어, [ONNX Runtime](https://onnxruntime.ai/)을 사용하여 모델을 로드하고 실행할 수 있습니다:
+
+```python
+>>> from transformers import AutoTokenizer
+>>> from optimum.onnxruntime import ORTModelForQuestionAnswering
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert_base_uncased_squad_onnx")
+>>> model = ORTModelForQuestionAnswering.from_pretrained("distilbert_base_uncased_squad_onnx")
+>>> inputs = tokenizer("What am I using?", "Using DistilBERT with ONNX Runtime!", return_tensors="pt")
+>>> outputs = model(**inputs)
+```
+
+Hub의 TensorFlow 체크포인트에 대해서도 동일한 프로세스가 적용됩니다. 예를 들어, [Keras organization](https://huggingface.co/keras-io)에서 순수한 TensorFlow 체크포인트를 내보내는 방법은 다음과 같습니다:
+
+```bash
+optimum-cli export onnx --model keras-io/transformers-qa distilbert_base_cased_squad_onnx/
+```
+
+### `optimum.onnxruntime`을 사용하여 🤗 Transformers 모델을 ONNX로 내보내기 [[exporting-a-transformers-model-to-onnx-with-optimumonnxruntime]]
+
+CLI 대신에 `optimum.onnxruntime`을 사용하여 프로그래밍 방식으로 🤗 Transformers 모델을 ONNX로 내보낼 수도 있습니다. 다음과 같이 진행하세요:
+
+```python
+>>> from optimum.onnxruntime import ORTModelForSequenceClassification
+>>> from transformers import AutoTokenizer
+
+>>> model_checkpoint = "distilbert_base_uncased_squad"
+>>> save_directory = "onnx/"
+
+>>> # Load a model from transformers and export it to ONNX
+>>> ort_model = ORTModelForSequenceClassification.from_pretrained(model_checkpoint, export=True)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_checkpoint)
+
+>>> # Save the onnx model and tokenizer
+>>> ort_model.save_pretrained(save_directory)
+>>> tokenizer.save_pretrained(save_directory)
+```
+
+### 지원되지 않는 아키텍처의 모델 내보내기 [[exporting-a-model-for-an-unsupported-architecture]]
+
+현재 내보낼 수 없는 모델을 지원하기 위해 기여하려면, 먼저 [`optimum.exporters.onnx`](https://huggingface.co/docs/optimum/exporters/onnx/overview)에서 지원되는지 확인한 후 지원되지 않는 경우에는 [🤗 Optimum에 기여](https://huggingface.co/docs/optimum/exporters/onnx/usage_guides/contribute)하세요.
+
+### `transformers.onnx`를 사용하여 모델 내보내기 [[exporting-a-model-with-transformersonnx]]
+
+
+
+`tranformers.onnx`는 더 이상 유지되지 않습니다. 위에서 설명한 대로 🤗 Optimum을 사용하여 모델을 내보내세요. 이 섹션은 향후 버전에서 제거될 예정입니다.
+
+
+
+🤗 Transformers 모델을 ONNX로 내보내려면 추가 종속성을 설치하세요:
+
+```bash
+pip install transformers[onnx]
+```
+
+`transformers.onnx` 패키지를 Python 모듈로 사용하여 준비된 구성을 사용하여 체크포인트를 내보냅니다:
+
+```bash
+python -m transformers.onnx --model=distilbert/distilbert-base-uncased onnx/
+```
+
+이렇게 하면 `--model` 인수에 정의된 체크포인트의 ONNX 그래프가 내보내집니다. 🤗 Hub에서 제공하는 체크포인트나 로컬에 저장된 체크포인트를 전달할 수 있습니다. 결과로 생성된 `model.onnx` 파일은 ONNX 표준을 지원하는 많은 가속기 중 하나에서 실행할 수 있습니다. 예를 들어, 다음과 같이 ONNX Runtime을 사용하여 모델을 로드하고 실행할 수 있습니다:
+
+```python
+>>> from transformers import AutoTokenizer
+>>> from onnxruntime import InferenceSession
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> session = InferenceSession("onnx/model.onnx")
+>>> # ONNX Runtime expects NumPy arrays as input
+>>> inputs = tokenizer("Using DistilBERT with ONNX Runtime!", return_tensors="np")
+>>> outputs = session.run(output_names=["last_hidden_state"], input_feed=dict(inputs))
+```
+
+필요한 출력 이름(예: `["last_hidden_state"]`)은 각 모델의 ONNX 구성을 확인하여 얻을 수 있습니다. 예를 들어, DistilBERT의 경우 다음과 같습니다:
+
+```python
+>>> from transformers.models.distilbert import DistilBertConfig, DistilBertOnnxConfig
+
+>>> config = DistilBertConfig()
+>>> onnx_config = DistilBertOnnxConfig(config)
+>>> print(list(onnx_config.outputs.keys()))
+["last_hidden_state"]
+```
+
+Hub의 TensorFlow 체크포인트에 대해서도 동일한 프로세스가 적용됩니다. 예를 들어, 다음과 같이 순수한 TensorFlow 체크포인트를 내보냅니다:
+
+```bash
+python -m transformers.onnx --model=keras-io/transformers-qa onnx/
+```
+
+로컬에 저장된 모델을 내보내려면 모델의 가중치 파일과 토크나이저 파일을 동일한 디렉토리에 저장한 다음, transformers.onnx 패키지의 --model 인수를 원하는 디렉토리로 지정하여 ONNX로 내보냅니다:
+
+```bash
+python -m transformers.onnx --model=local-pt-checkpoint onnx/
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/task_summary.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/task_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..a0e60c60924b99989eb14bcc322297c8d3bcc5d6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/task_summary.md
@@ -0,0 +1,341 @@
+
+
+# 🤗 Transformers로 할 수 있는 것[[what__transformers_can_do]]
+
+🤗 Transformers는 자연어처리(NLP), 컴퓨터 비전, 오디오 및 음성 처리 작업에 대한 사전훈련된 최첨단 모델 라이브러리입니다.
+이 라이브러리는 트랜스포머 모델뿐만 아니라 컴퓨터 비전 작업을 위한 현대적인 합성곱 신경망과 같은 트랜스포머가 아닌 모델도 포함하고 있습니다.
+
+스마트폰, 앱, 텔레비전과 같은 오늘날 가장 인기 있는 소비자 제품을 살펴보면, 딥러닝 기술이 그 뒤에 사용되고 있을 확률이 높습니다.
+스마트폰으로 촬영한 사진에서 배경 객체를 제거하고 싶다면 어떻게 할까요? 이는 파놉틱 세그멘테이션 작업의 예입니다(아직 이게 무엇인지 모른다면, 다음 섹션에서 설명하겠습니다!).
+
+이 페이지는 다양한 음성 및 오디오, 컴퓨터 비전, NLP 작업을 🤗 Transformers 라이브러리를 활용하여 다루는 간단한 예제를 3줄의 코드로 제공합니다.
+
+## 오디오[[audio]]
+
+
+음성 및 오디오 처리 작업은 다른 모달리티와 약간 다릅니다. 이는 주로 오디오가 연속적인 신호로 입력되기 때문입니다.
+텍스트와 달리 원본 오디오 파형(waveform)은 문장이 단어로 나눠지는 것처럼 깔끔하게 이산적인 묶음으로 나눌 수 없습니다.
+이를 극복하기 위해 원본 오디오 신호는 일정한 간격으로 샘플링됩니다. 해당 간격 내에서 더 많은 샘플을 취할 경우 샘플링률이 높아지며, 오디오는 원본 오디오 소스에 더 가까워집니다.
+
+과거의 접근 방식은 오디오에서 유용한 특징을 추출하기 위해 오디오를 전처리하는 것이었습니다.
+하지만 현재는 원본 오디오 파형을 특성 인코더에 직접 넣어서 오디오 표현(representation)을 추출하는 것이 더 일반적입니다.
+이렇게 하면 전처리 단계가 단순해지고 모델이 가장 중요한 특징을 학습할 수 있습니다.
+
+### 오디오 분류[[audio_classification]]
+
+
+오디오 분류는 오디오 데이터에 미리 정의된 클래스 집합의 레이블을 지정하는 작업입니다. 이는 많은 구체적인 응용 프로그램을 포함한 넓은 범주입니다.
+
+일부 예시는 다음과 같습니다:
+
+* 음향 장면 분류: 오디오에 장면 레이블("사무실", "해변", "경기장")을 지정합니다.
+* 음향 이벤트 감지: 오디오에 소리 이벤트 레이블("차 경적", "고래 울음소리", "유리 파손")을 지정합니다.
+* 태깅: 여러 가지 소리(새 지저귐, 회의에서의 화자 식별)가 포함된 오디오에 레이블을 지정합니다.
+* 음악 분류: 음악에 장르 레이블("메탈", "힙합", "컨트리")을 지정합니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="audio-classification", model="superb/hubert-base-superb-er")
+>>> preds = classifier("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.4532, 'label': 'hap'},
+ {'score': 0.3622, 'label': 'sad'},
+ {'score': 0.0943, 'label': 'neu'},
+ {'score': 0.0903, 'label': 'ang'}]
+```
+
+### 자동 음성 인식[[automatic_speech_recognition]]
+
+
+자동 음성 인식(ASR)은 음성을 텍스트로 변환하는 작업입니다.
+음성은 인간의 자연스러운 의사소통 형태이기 때문에 ASR은 가장 일반적인 오디오 작업 중 하나입니다.
+오늘날 ASR 시스템은 스피커, 전화 및 자동차와 같은 "스마트" 기술 제품에 내장되어 있습니다.
+우리는 가상 비서에게 음악 재생, 알림 설정 및 날씨 정보를 요청할 수 있습니다.
+
+하지만 트랜스포머 아키텍처가 해결하는 데 도움을 준 핵심 도전 과제 중 하나는 양이 데이터 양이 적은 언어(low-resource language)에 대한 것입니다. 대량의 음성 데이터로 사전 훈련한 후 데이터 양이 적은 언어에서 레이블이 지정된 음성 데이터 1시간만으로 모델을 미세 조정하면 이전의 100배 많은 레이블이 지정된 데이터로 훈련된 ASR 시스템보다 훨씬 더 높은 품질의 결과를 얻을 수 있습니다.
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline(task="automatic-speech-recognition", model="openai/whisper-small")
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
+```
+
+## 컴퓨터 비전[[computer_vision]]
+
+컴퓨터 비전 작업 중 가장 초기의 성공적인 작업 중 하나는 [합성곱 신경망(CNN)](glossary#convolution)을 사용하여 우편번호 숫자 이미지를 인식하는 것이었습니다. 이미지는 픽셀로 구성되어 있으며 각 픽셀은 숫자 값으로 표현됩니다. 이로써 이미지를 픽셀 값의 행렬로 나타내는 것이 쉬워집니다. 특정한 픽셀 값의 조합은 이미지의 색상을 의미합니다.
+
+컴퓨터 비전 작업은 일반적으로 다음 두 가지 방법으로 접근 가능합니다:
+
+1. 합성곱을 사용하여 이미지의 낮은 수준 특징에서 높은 수준의 추상적인 요소까지 계층적으로 학습합니다.
+
+2. 이미지를 패치로 나누고 트랜스포머를 사용하여 점진적으로 각 이미지 패치가 서로 어떠한 방식으로 연관되어 이미지를 형성하는지 학습합니다. `CNN`에서 선호하는 상향식 접근법과는 달리, 이 방식은 흐릿한 이미지로 초안을 그리고 점진적으로 선명한 이미지로 만들어가는 것과 유사합니다.
+
+### 이미지 분류[[image_classification]]
+
+
+이미지 분류는 한 개의 전체 이미지에 미리 정의된 클래스 집합의 레이블을 지정하는 작업입니다.
+
+대부분의 분류 작업과 마찬가지로, 이미지 분류에는 다양한 실용적인 용도가 있으며, 일부 예시는 다음과 같습니다:
+
+
+* 의료: 질병을 감지하거나 환자 건강을 모니터링하기 위해 의료 이미지에 레이블을 지정합니다.
+* 환경: 위성 이미지를 분류하여 산림 벌채를 감시하고 야생 지역 관리를 위한 정보를 제공하거나 산불을 감지합니다.
+* 농업: 작물 이미지를 분류하여 식물 건강을 확인하거나 위성 이미지를 분류하여 토지 이용 관찰에 사용합니다.
+* 생태학: 동물이나 식물 종 이미지를 분류하여 야생 동물 개체군을 조사하거나 멸종 위기에 처한 종을 추적합니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="image-classification")
+>>> preds = classifier(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> print(*preds, sep="\n")
+{'score': 0.4335, 'label': 'lynx, catamount'}
+{'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}
+{'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}
+{'score': 0.0239, 'label': 'Egyptian cat'}
+{'score': 0.0229, 'label': 'tiger cat'}
+```
+
+### 객체 탐지[[object_detection]]
+
+
+이미지 분류와 달리 객체 탐지는 이미지 내에서 여러 객체를 식별하고 바운딩 박스로 정의된 객체의 위치를 파악합니다.
+
+객체 탐지의 몇 가지 응용 예시는 다음과 같습니다:
+
+* 자율 주행 차량: 다른 차량, 보행자 및 신호등과 같은 일상적인 교통 객체를 감지합니다.
+* 원격 감지: 재난 모니터링, 도시 계획 및 기상 예측 등을 수행합니다.
+* 결함 탐지: 건물의 균열이나 구조적 손상, 제조 결함 등을 탐지합니다.
+
+
+```py
+>>> from transformers import pipeline
+
+>>> detector = pipeline(task="object-detection")
+>>> preds = detector(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"], "box": pred["box"]} for pred in preds]
+>>> preds
+[{'score': 0.9865,
+ 'label': 'cat',
+ 'box': {'xmin': 178, 'ymin': 154, 'xmax': 882, 'ymax': 598}}]
+```
+
+### 이미지 분할[[image_segmentation]]
+
+
+이미지 분할은 픽셀 차원의 작업으로, 이미지 내의 모든 픽셀을 클래스에 할당합니다. 이는 객체 탐지와 다릅니다. 객체 탐지는 바운딩 박스를 사용하여 이미지 내의 객체를 레이블링하고 예측하는 반면, 분할은 더 세분화된 작업입니다. 분할은 픽셀 수준에서 객체를 감지할 수 있습니다.
+
+이미지 분할에는 여러 유형이 있습니다:
+
+* 인스턴스 분할: 개체의 클래스를 레이블링하는 것 외에도, 개체의 각 구분된 인스턴스에도 레이블을 지정합니다 ("개-1", "개-2" 등).
+* 파놉틱 분할: 의미적 분할과 인스턴스 분할의 조합입니다. 각 픽셀을 의미적 클래스로 레이블링하는 **동시에** 개체의 각각 구분된 인스턴스로도 레이블을 지정합니다.
+
+분할 작업은 자율 주행 차량에서 유용하며, 주변 환경의 픽셀 수준 지도를 생성하여 보행자와 다른 차량 주변에서 안전하게 탐색할 수 있습니다. 또한 의료 영상에서도 유용합니다. 분할 작업이 픽셀 수준에서 객체를 감지할 수 있기 때문에 비정상적인 세포나 장기의 특징을 식별하는 데 도움이 될 수 있습니다. 이미지 분할은 의류 가상 시착이나 카메라를 통해 실제 세계에 가상 개체를 덧씌워 증강 현실 경험을 만드는 등 전자 상거래 분야에서도 사용될 수 있습니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> segmenter = pipeline(task="image-segmentation")
+>>> preds = segmenter(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> print(*preds, sep="\n")
+{'score': 0.9879, 'label': 'LABEL_184'}
+{'score': 0.9973, 'label': 'snow'}
+{'score': 0.9972, 'label': 'cat'}
+```
+
+### 깊이 추정[[depth_estimation]]
+
+깊이 추정은 카메라로부터 이미지 내부의 각 픽셀의 거리를 예측합니다. 이 컴퓨터 비전 작업은 특히 장면 이해와 재구성에 중요합니다. 예를 들어, 자율 주행 차량은 보행자, 교통 표지판 및 다른 차량과 같은 객체와의 거리를 이해하여 장애물과 충돌을 피해야 합니다. 깊이 정보는 또한 2D 이미지에서 3D 표현을 구성하는 데 도움이 되며 생물학적 구조나 건물의 고품질 3D 표현을 생성하는 데 사용될 수 있습니다.
+
+깊이 추정에는 두 가지 접근 방식이 있습니다:
+
+* 스테레오: 약간 다른 각도에서 촬영된 동일한 이미지 두 장을 비교하여 깊이를 추정합니다.
+* 단안: 단일 이미지에서 깊이를 추정합니다.
+
+
+```py
+>>> from transformers import pipeline
+
+>>> depth_estimator = pipeline(task="depth-estimation")
+>>> preds = depth_estimator(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+```
+
+## 자연어처리[[natural_language_processing]]
+
+텍스트는 인간이 의사 소통하는 자연스러운 방식 중 하나이기 때문에 자연어처리 역시 가장 일반적인 작업 유형 중 하나입니다. 모델이 인식하는 형식으로 텍스트를 변환하려면 토큰화해야 합니다. 이는 텍스트 시퀀스를 개별 단어 또는 하위 단어(토큰)로 분할한 다음 이러한 토큰을 숫자로 변환하는 것을 의미합니다. 결과적으로 텍스트 시퀀스를 숫자 시퀀스로 표현할 수 있으며, 숫자 시퀀스를 다양한 자연어처리 작업을 해결하기 위한 모델에 입력할 수 있습니다!
+
+### 텍스트 분류[[text_classification]]
+
+다른 모달리티에서의 분류 작업과 마찬가지로 텍스트 분류는 미리 정의된 클래스 집합에서 텍스트 시퀀스(문장 수준, 단락 또는 문서 등)에 레이블을 지정합니다. 텍스트 분류에는 다양한 실용적인 응용 사례가 있으며, 일부 예시는 다음과 같습니다:
+
+* 감성 분석: 텍스트를 `긍정` 또는 `부정`과 같은 어떤 극성에 따라 레이블링하여 정치, 금융, 마케팅과 같은 분야에서 의사 결정에 정보를 제공하고 지원할 수 있습니다.
+* 콘텐츠 분류: 텍스트를 주제에 따라 레이블링(날씨, 스포츠, 금융 등)하여 뉴스 및 소셜 미디어 피드에서 정보를 구성하고 필터링하는 데 도움이 될 수 있습니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="sentiment-analysis")
+>>> preds = classifier("Hugging Face is the best thing since sliced bread!")
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.9991, 'label': 'POSITIVE'}]
+```
+
+### 토큰 분류[[token_classification]]
+
+모든 자연어처리 작업에서는 텍스트가 개별 단어나 하위 단어로 분리되어 전처리됩니다. 분리된 단어를 [토큰](/glossary#token)이라고 합니다. 토큰 분류는 각 토큰에 미리 정의된 클래스 집합의 레이블을 할당합니다.
+
+토큰 분류의 두 가지 일반적인 유형은 다음과 같습니다:
+
+* 개체명 인식 (NER): 토큰을 조직, 인물, 위치 또는 날짜와 같은 개체 범주에 따라 레이블링합니다. NER은 특히 유전체학적인 환경에서 유전자, 단백질 및 약물 이름에 레이블을 지정하는 데 널리 사용됩니다.
+* 품사 태깅 (POS): 명사, 동사, 형용사와 같은 품사에 따라 토큰에 레이블을 할당합니다. POS는 번역 시스템이 동일한 단어가 문법적으로 어떻게 다른지 이해하는 데 도움이 됩니다 (명사로 사용되는 "bank(은행)"과 동사로 사용되는 "bank(예금을 예치하다)"과 같은 경우).
+
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="ner")
+>>> preds = classifier("Hugging Face is a French company based in New York City.")
+>>> preds = [
+... {
+... "entity": pred["entity"],
+... "score": round(pred["score"], 4),
+... "index": pred["index"],
+... "word": pred["word"],
+... "start": pred["start"],
+... "end": pred["end"],
+... }
+... for pred in preds
+... ]
+>>> print(*preds, sep="\n")
+{'entity': 'I-ORG', 'score': 0.9968, 'index': 1, 'word': 'Hu', 'start': 0, 'end': 2}
+{'entity': 'I-ORG', 'score': 0.9293, 'index': 2, 'word': '##gging', 'start': 2, 'end': 7}
+{'entity': 'I-ORG', 'score': 0.9763, 'index': 3, 'word': 'Face', 'start': 8, 'end': 12}
+{'entity': 'I-MISC', 'score': 0.9983, 'index': 6, 'word': 'French', 'start': 18, 'end': 24}
+{'entity': 'I-LOC', 'score': 0.999, 'index': 10, 'word': 'New', 'start': 42, 'end': 45}
+{'entity': 'I-LOC', 'score': 0.9987, 'index': 11, 'word': 'York', 'start': 46, 'end': 50}
+{'entity': 'I-LOC', 'score': 0.9992, 'index': 12, 'word': 'City', 'start': 51, 'end': 55}
+```
+
+### 질의응답[[question_answering]]
+
+질의응답은 또 하나의 토큰 차원의 작업으로, 문맥이 있을 때(개방형 도메인)와 문맥이 없을 때(폐쇄형 도메인) 질문에 대한 답변을 반환합니다. 이 작업은 가상 비서에게 식당이 영업 중인지와 같은 질문을 할 때마다 발생할 수 있습니다. 고객 지원 또는 기술 지원을 제공하거나 검색 엔진이 요청한 정보를 검색하는 데 도움을 줄 수 있습니다.
+
+질문 답변에는 일반적으로 두 가지 유형이 있습니다:
+
+* 추출형: 질문과 문맥이 주어졌을 때, 모델이 주어진 문맥의 일부에서 가져온 텍스트의 범위를 답변으로 합니다.
+* 생성형: 질문과 문맥이 주어졌을 때, 주어진 문맥을 통해 답변을 생성합니다. 이 접근 방식은 [`QuestionAnsweringPipeline`] 대신 [`Text2TextGenerationPipeline`]을 통해 처리됩니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> question_answerer = pipeline(task="question-answering")
+>>> preds = question_answerer(
+... question="What is the name of the repository?",
+... context="The name of the repository is huggingface/transformers",
+... )
+>>> print(
+... f"score: {round(preds['score'], 4)}, start: {preds['start']}, end: {preds['end']}, answer: {preds['answer']}"
+... )
+score: 0.9327, start: 30, end: 54, answer: huggingface/transformers
+```
+
+### 요약[[summarization]]
+
+요약은 원본 문서의 의미를 최대한 보존하면서 긴 문서를 짧은 문서로 만드는 작업입니다. 요약은 `sequence-to-sequence` 작업입니다. 입력보다 짧은 텍스트 시퀀스를 출력합니다. 요약 작업은 독자가 장문 문서들의 주요 포인트를 빠르게 이해하는 데 도움을 줄 수 있습니다. 입법안, 법률 및 금융 문서, 특허 및 과학 논문은 요약 작업이 독자의 시간을 절약하고 독서 보조 도구로 사용될 수 있는 몇 가지 예시입니다.
+
+질문 답변과 마찬가지로 요약에는 두 가지 유형이 있습니다:
+
+* 추출형: 원본 텍스트에서 가장 중요한 문장을 식별하고 추출합니다.
+* 생성형: 원본 텍스트에서 목표 요약을 생성합니다. 입력 문서에 없는 새로운 단어를 포함할 수도 있습니다. [`SummarizationPipeline`]은 생성형 접근 방식을 사용합니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> summarizer = pipeline(task="summarization")
+>>> summarizer(
+... "In this work, we presented the Transformer, the first sequence transduction model based entirely on attention, replacing the recurrent layers most commonly used in encoder-decoder architectures with multi-headed self-attention. For translation tasks, the Transformer can be trained significantly faster than architectures based on recurrent or convolutional layers. On both WMT 2014 English-to-German and WMT 2014 English-to-French translation tasks, we achieve a new state of the art. In the former task our best model outperforms even all previously reported ensembles."
+... )
+[{'summary_text': ' The Transformer is the first sequence transduction model based entirely on attention . It replaces the recurrent layers most commonly used in encoder-decoder architectures with multi-headed self-attention . For translation tasks, the Transformer can be trained significantly faster than architectures based on recurrent or convolutional layers .'}]
+```
+
+### 번역[[translation]]
+
+번역은 한 언어로 된 텍스트 시퀀스를 다른 언어로 변환하는 작업입니다. 이는 서로 다른 배경을 가진 사람들이 서로 소통하는 데 도움을 주는 중요한 역할을 합니다. 더 넓은 대중에게 콘텐츠를 번역하여 전달하거나, 새로운 언어를 배우는 데 도움이 되는 학습 도구가 될 수도 있습니다. 요약과 마찬가지로, 번역은 `sequence-to-sequence` 작업입니다. 즉, 모델은 입력 시퀀스를 받아서 출력이 되는 목표 시퀀스를 반환합니다.
+
+초기의 번역 모델은 대부분 단일 언어로 이루어져 있었지만, 최근에는 많은 언어 쌍 간에 번역을 수행할 수 있는 다중 언어 모델에 대한 관심이 높아지고 있습니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> text = "translate English to French: Hugging Face is a community-based open-source platform for machine learning."
+>>> translator = pipeline(task="translation", model="google-t5/t5-small")
+>>> translator(text)
+[{'translation_text': "Hugging Face est une tribune communautaire de l'apprentissage des machines."}]
+```
+
+### 언어 모델링[[language_modeling]]
+
+언어 모델링은 텍스트 시퀀스에서 단어를 예측하는 작업입니다. 사전 훈련된 언어 모델은 많은 다른 하위 작업에 따라 미세 조정될 수 있기 때문에 매우 인기 있는 자연어처리 작업이 되었습니다. 최근에는 제로 샷(zero-shot) 또는 퓨 샷(few-shot) 학습이 가능한 대규모 언어 모델(Large Language Models, LLM)에 대한 많은 관심이 발생하고 있습니다. 이는 모델이 명시적으로 훈련되지 않은 작업도 해결할 수 있다는 것을 의미합니다! 언어 모델은 유창하고 설득력 있는 텍스트를 생성하는 데 사용될 수 있지만, 텍스트가 항상 정확하지는 않을 수 있으므로 주의가 필요합니다.
+
+언어 모델링에는 두 가지 유형이 있습니다:
+
+* 인과적 언어 모델링: 이 모델의 목적은 시퀀스에서 다음 토큰을 예측하는 것이며, 미래 토큰이 마스킹 됩니다.
+ ```py
+ >>> from transformers import pipeline
+
+ >>> prompt = "Hugging Face is a community-based open-source platform for machine learning."
+ >>> generator = pipeline(task="text-generation")
+ >>> generator(prompt) # doctest: +SKIP
+ ```
+
+* 마스킹된 언어 모델링: 이 모델의 목적은 시퀀스 내의 마스킹된 토큰을 예측하는 것이며, 시퀀스 내의 모든 토큰에 대한 접근이 제공됩니다.
+
+ ```py
+ >>> text = "Hugging Face is a community-based open-source for machine learning."
+ >>> fill_mask = pipeline(task="fill-mask")
+ >>> preds = fill_mask(text, top_k=1)
+ >>> preds = [
+ ... {
+ ... "score": round(pred["score"], 4),
+ ... "token": pred["token"],
+ ... "token_str": pred["token_str"],
+ ... "sequence": pred["sequence"],
+ ... }
+ ... for pred in preds
+ ... ]
+ >>> preds
+ [{'score': 0.2236,
+ 'token': 1761,
+ 'token_str': ' platform',
+ 'sequence': 'Hugging Face is a community-based open-source platform for machine learning.'}]
+ ```
+
+이 페이지를 통해 각 모달리티의 다양한 작업 유형과 각 작업의 실용적 중요성에 대해 추가적인 배경 정보를 얻으셨기를 바랍니다. 다음 [섹션](tasks_explained)에서는 🤗 Transformer가 이러한 작업을 해결하는 **방법**에 대해 알아보실 수 있습니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/asr.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/asr.md
new file mode 100644
index 0000000000000000000000000000000000000000..d1e4a5e1d919831fc18ebbc36b82a2fb8269dcbc
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/asr.md
@@ -0,0 +1,375 @@
+
+
+# 자동 음성 인식[[automatic-speech-recognition]]
+
+[[open-in-colab]]
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/automatic-speech-recognition)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate jiwer
+```
+
+Hugging Face 계정에 로그인하면 모델을 업로드하고 커뮤니티에 공유할 수 있습니다. 토큰을 입력하여 로그인하세요.
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## MInDS-14 데이터 세트 가져오기[[load-minds-14-dataset]]
+
+먼저, 🤗 Datasets 라이브러리에서 [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) 데이터 세트의 일부분을 가져오세요.
+이렇게 하면 전체 데이터 세트에 대한 훈련에 시간을 들이기 전에 모든 것이 작동하는지 실험하고 검증할 수 있습니다.
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> minds = load_dataset("PolyAI/minds14", name="en-US", split="train[:100]")
+```
+
+[`~Dataset.train_test_split`] 메소드를 사용하여 데이터 세트의 `train`을 훈련 세트와 테스트 세트로 나누세요:
+
+```py
+>>> minds = minds.train_test_split(test_size=0.2)
+```
+
+그리고 데이터 세트를 확인하세요:
+
+```py
+>>> minds
+DatasetDict({
+ train: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 16
+ })
+ test: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 4
+ })
+})
+```
+
+데이터 세트에는 `lang_id`와 `english_transcription`과 같은 유용한 정보가 많이 포함되어 있지만, 이 가이드에서는 `audio`와 `transcription`에 초점을 맞출 것입니다. 다른 열은 [`~datasets.Dataset.remove_columns`] 메소드를 사용하여 제거하세요:
+
+```py
+>>> minds = minds.remove_columns(["english_transcription", "intent_class", "lang_id"])
+```
+
+예시를 다시 한번 확인해보세요:
+
+```py
+>>> minds["train"][0]
+{'audio': {'array': array([-0.00024414, 0. , 0. , ..., 0.00024414,
+ 0.00024414, 0.00024414], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'sampling_rate': 8000},
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'transcription': "hi I'm trying to use the banking app on my phone and currently my checking and savings account balance is not refreshing"}
+```
+
+두 개의 필드가 있습니다:
+
+- `audio`: 오디오 파일을 가져오고 리샘플링하기 위해 호출해야 하는 음성 신호의 1차원 `array(배열)`
+- `transcription`: 목표 텍스트
+
+## 전처리[[preprocess]]
+
+다음으로 오디오 신호를 처리하기 위한 Wav2Vec2 프로세서를 가져옵니다:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base")
+```
+
+MInDS-14 데이터 세트의 샘플링 레이트는 8000kHz이므로([데이터 세트 카드](https://huggingface.co/datasets/PolyAI/minds14)에서 확인), 사전 훈련된 Wav2Vec2 모델을 사용하려면 데이터 세트를 16000kHz로 리샘플링해야 합니다:
+
+```py
+>>> minds = minds.cast_column("audio", Audio(sampling_rate=16_000))
+>>> minds["train"][0]
+{'audio': {'array': array([-2.38064706e-04, -1.58618059e-04, -5.43987835e-06, ...,
+ 2.78103951e-04, 2.38446111e-04, 1.18740834e-04], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'sampling_rate': 16000},
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'transcription': "hi I'm trying to use the banking app on my phone and currently my checking and savings account balance is not refreshing"}
+```
+
+위의 'transcription'에서 볼 수 있듯이 텍스트는 대문자와 소문자가 섞여 있습니다. Wav2Vec2 토크나이저는 대문자 문자에 대해서만 훈련되어 있으므로 텍스트가 토크나이저의 어휘와 일치하는지 확인해야 합니다:
+
+```py
+>>> def uppercase(example):
+... return {"transcription": example["transcription"].upper()}
+
+
+>>> minds = minds.map(uppercase)
+```
+
+이제 다음 작업을 수행할 전처리 함수를 만들어보겠습니다:
+
+1. `audio` 열을 호출하여 오디오 파일을 가져오고 리샘플링합니다.
+2. 오디오 파일에서 `input_values`를 추출하고 프로세서로 `transcription` 열을 토큰화합니다.
+
+```py
+>>> def prepare_dataset(batch):
+... audio = batch["audio"]
+... batch = processor(audio["array"], sampling_rate=audio["sampling_rate"], text=batch["transcription"])
+... batch["input_length"] = len(batch["input_values"][0])
+... return batch
+```
+
+전체 데이터 세트에 전처리 함수를 적용하려면 🤗 Datasets [`~datasets.Dataset.map`] 함수를 사용하세요. `num_proc` 매개변수를 사용하여 프로세스 수를 늘리면 `map`의 속도를 높일 수 있습니다. [`~datasets.Dataset.remove_columns`] 메소드를 사용하여 필요하지 않은 열을 제거하세요:
+
+```py
+>>> encoded_minds = minds.map(prepare_dataset, remove_columns=minds.column_names["train"], num_proc=4)
+```
+
+🤗 Transformers에는 자동 음성 인식용 데이터 콜레이터가 없으므로 예제 배치를 생성하려면 [`DataCollatorWithPadding`]을 조정해야 합니다. 이렇게 하면 데이터 콜레이터는 텍스트와 레이블을 배치에서 가장 긴 요소의 길이에 동적으로 패딩하여 길이를 균일하게 합니다. `tokenizer` 함수에서 `padding=True`를 설정하여 텍스트를 패딩할 수 있지만, 동적 패딩이 더 효율적입니다.
+
+다른 데이터 콜레이터와 달리 이 특정 데이터 콜레이터는 `input_values`와 `labels`에 대해 다른 패딩 방법을 적용해야 합니다.
+
+```py
+>>> import torch
+
+>>> from dataclasses import dataclass, field
+>>> from typing import Any, Dict, List, Optional, Union
+
+
+>>> @dataclass
+... class DataCollatorCTCWithPadding:
+... processor: AutoProcessor
+... padding: Union[bool, str] = "longest"
+
+... def __call__(self, features: List[Dict[str, Union[List[int], torch.Tensor]]]) -> Dict[str, torch.Tensor]:
+... # 입력과 레이블을 분할합니다
+... # 길이가 다르고, 각각 다른 패딩 방법을 사용해야 하기 때문입니다
+... input_features = [{"input_values": feature["input_values"][0]} for feature in features]
+... label_features = [{"input_ids": feature["labels"]} for feature in features]
+
+... batch = self.processor.pad(input_features, padding=self.padding, return_tensors="pt")
+
+... labels_batch = self.processor.pad(labels=label_features, padding=self.padding, return_tensors="pt")
+
+... # 패딩에 대해 손실을 적용하지 않도록 -100으로 대체합니다
+... labels = labels_batch["input_ids"].masked_fill(labels_batch.attention_mask.ne(1), -100)
+
+... batch["labels"] = labels
+
+... return batch
+```
+
+이제 `DataCollatorForCTCWithPadding`을 인스턴스화합니다:
+
+```py
+>>> data_collator = DataCollatorCTCWithPadding(processor=processor, padding="longest")
+```
+
+## 평가하기[[evaluate]]
+
+훈련 중에 평가 지표를 포함하면 모델의 성능을 평가하는 데 도움이 되는 경우가 많습니다. 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리를 사용하면 평가 방법을 빠르게 불러올 수 있습니다.
+이 작업에서는 [단어 오류율(Word Error Rate, WER)](https://huggingface.co/spaces/evaluate-metric/wer) 평가 지표를 가져옵니다.
+(평가 지표를 불러오고 계산하는 방법은 🤗 Evaluate [둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하세요):
+
+```py
+>>> import evaluate
+
+>>> wer = evaluate.load("wer")
+```
+
+그런 다음 예측값과 레이블을 [`~evaluate.EvaluationModule.compute`]에 전달하여 WER을 계산하는 함수를 만듭니다:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(pred):
+... pred_logits = pred.predictions
+... pred_ids = np.argmax(pred_logits, axis=-1)
+
+... pred.label_ids[pred.label_ids == -100] = processor.tokenizer.pad_token_id
+
+... pred_str = processor.batch_decode(pred_ids)
+... label_str = processor.batch_decode(pred.label_ids, group_tokens=False)
+
+... wer = wer.compute(predictions=pred_str, references=label_str)
+
+... return {"wer": wer}
+```
+
+이제 `compute_metrics` 함수를 사용할 준비가 되었으며, 훈련을 설정할 때 이 함수로 되돌아올 것입니다.
+
+## 훈련하기[[train]]
+
+
+
+
+
+[`Trainer`]로 모델을 미세 조정하는 것이 익숙하지 않다면, [여기](../training#train-with-pytorch-trainer)에서 기본 튜토리얼을 확인해보세요!
+
+
+
+이제 모델 훈련을 시작할 준비가 되었습니다! [`AutoModelForCTC`]로 Wav2Vec2를 가져오세요. `ctc_loss_reduction` 매개변수로 CTC 손실에 적용할 축소(reduction) 방법을 지정하세요. 기본값인 합계 대신 평균을 사용하는 것이 더 좋은 경우가 많습니다:
+
+```py
+>>> from transformers import AutoModelForCTC, TrainingArguments, Trainer
+
+>>> model = AutoModelForCTC.from_pretrained(
+... "facebook/wav2vec2-base",
+... ctc_loss_reduction="mean",
+... pad_token_id=processor.tokenizer.pad_token_id,
+... )
+```
+
+이제 세 단계만 남았습니다:
+
+1. [`TrainingArguments`]에서 훈련 하이퍼파라미터를 정의하세요. `output_dir`은 모델을 저장할 경로를 지정하는 유일한 필수 매개변수입니다. `push_to_hub=True`를 설정하여 모델을 Hub에 업로드 할 수 있습니다(모델을 업로드하려면 Hugging Face에 로그인해야 합니다). [`Trainer`]는 각 에폭마다 WER을 평가하고 훈련 체크포인트를 저장합니다.
+2. 모델, 데이터 세트, 토크나이저, 데이터 콜레이터, `compute_metrics` 함수와 함께 [`Trainer`]에 훈련 인수를 전달하세요.
+3. [`~Trainer.train`]을 호출하여 모델을 미세 조정하세요.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_asr_mind_model",
+... per_device_train_batch_size=8,
+... gradient_accumulation_steps=2,
+... learning_rate=1e-5,
+... warmup_steps=500,
+... max_steps=2000,
+... gradient_checkpointing=True,
+... fp16=True,
+... group_by_length=True,
+... eval_strategy="steps",
+... per_device_eval_batch_size=8,
+... save_steps=1000,
+... eval_steps=1000,
+... logging_steps=25,
+... load_best_model_at_end=True,
+... metric_for_best_model="wer",
+... greater_is_better=False,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=encoded_minds["train"],
+... eval_dataset=encoded_minds["test"],
+... processing_class=processor.feature_extractor,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면 모두가 모델을 사용할 수 있도록 [`~transformers.Trainer.push_to_hub`] 메소드를 사용하여 모델을 Hub에 공유하세요:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+자동 음성 인식을 위해 모델을 미세 조정하는 더 자세한 예제는 영어 자동 음성 인식을 위한 [블로그 포스트](https://huggingface.co/blog/fine-tune-wav2vec2-english)와 다국어 자동 음성 인식을 위한 [포스트](https://huggingface.co/blog/fine-tune-xlsr-wav2vec2)를 참조하세요.
+
+
+
+## 추론하기[[inference]]
+
+좋아요, 이제 모델을 미세 조정했으니 추론에 사용할 수 있습니다!
+
+추론에 사용할 오디오 파일을 가져오세요. 필요한 경우 오디오 파일의 샘플링 비율을 모델의 샘플링 레이트에 맞게 리샘플링하는 것을 잊지 마세요!
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", "en-US", split="train")
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
+>>> sampling_rate = dataset.features["audio"].sampling_rate
+>>> audio_file = dataset[0]["audio"]["path"]
+```
+
+추론을 위해 미세 조정된 모델을 시험해보는 가장 간단한 방법은 [`pipeline`]을 사용하는 것입니다. 모델을 사용하여 자동 음성 인식을 위한 `pipeline`을 인스턴스화하고 오디오 파일을 전달하세요:
+
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline("automatic-speech-recognition", model="stevhliu/my_awesome_asr_minds_model")
+>>> transcriber(audio_file)
+{'text': 'I WOUD LIKE O SET UP JOINT ACOUNT WTH Y PARTNER'}
+```
+
+
+
+텍스트로 변환된 결과가 꽤 괜찮지만 더 좋을 수도 있습니다! 더 나은 결과를 얻으려면 더 많은 예제로 모델을 미세 조정하세요!
+
+
+
+`pipeline`의 결과를 수동으로 재현할 수도 있습니다:
+
+
+
+오디오 파일과 텍스트를 전처리하고 PyTorch 텐서로 `input`을 반환할 프로세서를 가져오세요:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("stevhliu/my_awesome_asr_mind_model")
+>>> inputs = processor(dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
+```
+
+입력을 모델에 전달하고 로짓을 반환하세요:
+
+```py
+>>> from transformers import AutoModelForCTC
+
+>>> model = AutoModelForCTC.from_pretrained("stevhliu/my_awesome_asr_mind_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+가장 높은 확률의 `input_ids`를 예측하고, 프로세서를 사용하여 예측된 `input_ids`를 다시 텍스트로 디코딩하세요:
+
+```py
+>>> import torch
+
+>>> predicted_ids = torch.argmax(logits, dim=-1)
+>>> transcription = processor.batch_decode(predicted_ids)
+>>> transcription
+['I WOUL LIKE O SET UP JOINT ACOUNT WTH Y PARTNER']
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/audio_classification.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/audio_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..2defa691edef75ffaefb7a66a3d8ebfc3a95ae5e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/audio_classification.md
@@ -0,0 +1,324 @@
+
+
+# 오디오 분류[[audio_classification]]
+
+[[open-in-colab]]
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/audio-classification)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+모델을 업로드하고 커뮤니티와 공유할 수 있도록 허깅페이스 계정에 로그인하는 것이 좋습니다. 메시지가 표시되면 토큰을 입력하여 로그인합니다:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## MInDS-14 데이터셋 불러오기[[load_minds_14_dataset]]
+
+먼저 🤗 Datasets 라이브러리에서 MinDS-14 데이터 세트를 가져옵니다:
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> minds = load_dataset("PolyAI/minds14", name="en-US", split="train")
+```
+
+데이터 세트의 `train` 분할을 [`~datasets.Dataset.train_test_split`] 메소드를 사용하여 더 작은 훈련 및 테스트 집합으로 분할합니다. 이렇게 하면 전체 데이터 세트에 더 많은 시간을 소비하기 전에 모든 것이 작동하는지 실험하고 확인할 수 있습니다.
+
+```py
+>>> minds = minds.train_test_split(test_size=0.2)
+```
+
+이제 데이터 집합을 살펴볼게요:
+
+```py
+>>> minds
+DatasetDict({
+ train: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 450
+ })
+ test: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 113
+ })
+})
+```
+
+데이터 세트에는 `lang_id` 및 `english_transcription`과 같은 유용한 정보가 많이 포함되어 있지만 이 가이드에서는 `audio` 및 `intent_class`에 중점을 둘 것입니다. 다른 열은 [`~datasets.Dataset.remove_columns`] 메소드를 사용하여 제거합니다:
+
+```py
+>>> minds = minds.remove_columns(["path", "transcription", "english_transcription", "lang_id"])
+```
+
+예시를 살펴보겠습니다:
+
+```py
+>>> minds["train"][0]
+{'audio': {'array': array([ 0. , 0. , 0. , ..., -0.00048828,
+ -0.00024414, -0.00024414], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602b9a5fbb1e6d0fbce91f52.wav',
+ 'sampling_rate': 8000},
+ 'intent_class': 2}
+```
+
+두 개의 필드가 있습니다:
+
+- `audio`: 오디오 파일을 가져오고 리샘플링하기 위해 호출해야 하는 음성 신호의 1차원 `배열`입니다.
+- `intent_class`: 화자의 의도에 대한 클래스 ID를 나타냅니다.
+
+모델이 레이블 ID에서 레이블 이름을 쉽게 가져올 수 있도록 레이블 이름을 정수로 매핑하는 사전을 만들거나 그 반대로 매핑하는 사전을 만듭니다:
+
+```py
+>>> labels = minds["train"].features["intent_class"].names
+>>> label2id, id2label = dict(), dict()
+>>> for i, label in enumerate(labels):
+... label2id[label] = str(i)
+... id2label[str(i)] = label
+```
+
+이제 레이블 ID를 레이블 이름으로 변환할 수 있습니다:
+
+```py
+>>> id2label[str(2)]
+'app_error'
+```
+
+## 전처리[[preprocess]]
+
+다음 단계는 오디오 신호를 처리하기 위해 Wav2Vec2 특징 추출기를 가져오는 것입니다:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2-base")
+```
+
+MinDS-14 데이터 세트의 샘플링 속도는 8khz이므로(이 정보는 [데이터세트 카드](https://huggingface.co/datasets/PolyAI/minds14)에서 확인할 수 있습니다), 사전 훈련된 Wav2Vec2 모델을 사용하려면 데이터 세트를 16kHz로 리샘플링해야 합니다:
+
+```py
+>>> minds = minds.cast_column("audio", Audio(sampling_rate=16_000))
+>>> minds["train"][0]
+{'audio': {'array': array([ 2.2098757e-05, 4.6582241e-05, -2.2803260e-05, ...,
+ -2.8419291e-04, -2.3305941e-04, -1.1425107e-04], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602b9a5fbb1e6d0fbce91f52.wav',
+ 'sampling_rate': 16000},
+ 'intent_class': 2}
+```
+
+이제 전처리 함수를 만듭니다:
+
+1. 가져올 `오디오` 열을 호출하고 필요한 경우 오디오 파일을 리샘플링합니다.
+2. 오디오 파일의 샘플링 속도가 모델에 사전 훈련된 오디오 데이터의 샘플링 속도와 일치하는지 확인합니다. 이 정보는 Wav2Vec2 [모델 카드](https://huggingface.co/facebook/wav2vec2-base)에서 확인할 수 있습니다.
+3. 긴 입력이 잘리지 않고 일괄 처리되도록 최대 입력 길이를 설정합니다.
+
+```py
+>>> def preprocess_function(examples):
+... audio_arrays = [x["array"] for x in examples["audio"]]
+... inputs = feature_extractor(
+... audio_arrays, sampling_rate=feature_extractor.sampling_rate, max_length=16000, truncation=True
+... )
+... return inputs
+```
+
+전체 데이터 세트에 전처리 기능을 적용하려면 🤗 Datasets [`~datasets.Dataset.map`] 함수를 사용합니다. `batched=True`를 설정하여 데이터 집합의 여러 요소를 한 번에 처리하면 `map`의 속도를 높일 수 있습니다. 필요하지 않은 열을 제거하고 `intent_class`의 이름을 모델이 예상하는 이름인 `label`로 변경합니다:
+
+```py
+>>> encoded_minds = minds.map(preprocess_function, remove_columns="audio", batched=True)
+>>> encoded_minds = encoded_minds.rename_column("intent_class", "label")
+```
+
+## 평가하기[[evaluate]]
+
+훈련 중에 메트릭을 포함하면 모델의 성능을 평가하는 데 도움이 되는 경우가 많습니다. 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리를 사용하여 평가 방법을 빠르게 가져올 수 있습니다. 이 작업에서는 [accuracy(정확도)](https://huggingface.co/spaces/evaluate-metric/accuracy) 메트릭을 가져옵니다(메트릭을 가져오고 계산하는 방법에 대한 자세한 내용은 🤗 Evalutate [빠른 둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour) 참조하세요):
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+그런 다음 예측과 레이블을 [`~evaluate.EvaluationModule.compute`]에 전달하여 정확도를 계산하는 함수를 만듭니다:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions = np.argmax(eval_pred.predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=eval_pred.label_ids)
+```
+
+이제 `compute_metrics` 함수를 사용할 준비가 되었으며, 트레이닝을 설정할 때 이 함수를 사용합니다.
+
+## 훈련[[train]]
+
+
+
+
+
+[`Trainer`]로 모델을 미세 조정하는 데 익숙하지 않다면 기본 튜토리얼 [여기](../training#train-with-pytorch-trainer)을 살펴보세요!
+
+
+
+이제 모델 훈련을 시작할 준비가 되었습니다! [`AutoModelForAudioClassification`]을 이용해서 Wav2Vec2를 불러옵니다. 예상되는 레이블 수와 레이블 매핑을 지정합니다:
+
+```py
+>>> from transformers import AutoModelForAudioClassification, TrainingArguments, Trainer
+
+>>> num_labels = len(id2label)
+>>> model = AutoModelForAudioClassification.from_pretrained(
+... "facebook/wav2vec2-base", num_labels=num_labels, label2id=label2id, id2label=id2label
+... )
+```
+
+이제 세 단계만 남았습니다:
+
+1. 훈련 하이퍼파라미터를 [`TrainingArguments`]에 정의합니다. 유일한 필수 매개변수는 모델을 저장할 위치를 지정하는 `output_dir`입니다. `push_to_hub = True`를 설정하여 이 모델을 허브로 푸시합니다(모델을 업로드하려면 허깅 페이스에 로그인해야 합니다). 각 에폭이 끝날 때마다 [`Trainer`]가 정확도를 평가하고 훈련 체크포인트를 저장합니다.
+2. 모델, 데이터 세트, 토크나이저, 데이터 콜레이터, `compute_metrics` 함수와 함께 훈련 인자를 [`Trainer`]에 전달합니다.
+3. [`~Trainer.train`]을 호출하여 모델을 미세 조정합니다.
+
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_mind_model",
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... learning_rate=3e-5,
+... per_device_train_batch_size=32,
+... gradient_accumulation_steps=4,
+... per_device_eval_batch_size=32,
+... num_train_epochs=10,
+... warmup_ratio=0.1,
+... logging_steps=10,
+... load_best_model_at_end=True,
+... metric_for_best_model="accuracy",
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=encoded_minds["train"],
+... eval_dataset=encoded_minds["test"],
+... processing_class=feature_extractor,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면 모든 사람이 모델을 사용할 수 있도록 [`~transformers.Trainer.push_to_hub`] 메소드를 사용하여 모델을 허브에 공유하세요:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+For a more in-depth example of how to finetune a model for audio classification, take a look at the corresponding [PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/audio_classification.ipynb).
+
+
+
+## 추론[[inference]]
+
+이제 모델을 미세 조정했으니 추론에 사용할 수 있습니다!
+
+추론을 실행할 오디오 파일을 가져옵니다. 필요한 경우 오디오 파일의 샘플링 속도를 모델의 샘플링 속도와 일치하도록 리샘플링하는 것을 잊지 마세요!
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train")
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
+>>> sampling_rate = dataset.features["audio"].sampling_rate
+>>> audio_file = dataset[0]["audio"]["path"]
+```
+
+추론을 위해 미세 조정한 모델을 시험해 보는 가장 간단한 방법은 [`pipeline`]에서 사용하는 것입니다. 모델을 사용하여 오디오 분류를 위한 `pipeline`을 인스턴스화하고 오디오 파일을 전달합니다:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("audio-classification", model="stevhliu/my_awesome_minds_model")
+>>> classifier(audio_file)
+[
+ {'score': 0.09766869246959686, 'label': 'cash_deposit'},
+ {'score': 0.07998877018690109, 'label': 'app_error'},
+ {'score': 0.0781070664525032, 'label': 'joint_account'},
+ {'score': 0.07667109370231628, 'label': 'pay_bill'},
+ {'score': 0.0755252093076706, 'label': 'balance'}
+]
+```
+
+원하는 경우 `pipeline`의 결과를 수동으로 복제할 수도 있습니다:
+
+
+
+특징 추출기를 가져와서 오디오 파일을 전처리하고 `입력`을 PyTorch 텐서로 반환합니다:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("stevhliu/my_awesome_minds_model")
+>>> inputs = feature_extractor(dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
+```
+
+모델에 입력을 전달하고 로짓을 반환합니다:
+
+```py
+>>> from transformers import AutoModelForAudioClassification
+
+>>> model = AutoModelForAudioClassification.from_pretrained("stevhliu/my_awesome_minds_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+확률이 가장 높은 클래스를 가져온 다음 모델의 `id2label` 매핑을 사용하여 이를 레이블로 변환합니다:
+
+```py
+>>> import torch
+
+>>> predicted_class_ids = torch.argmax(logits).item()
+>>> predicted_label = model.config.id2label[predicted_class_ids]
+>>> predicted_label
+'cash_deposit'
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/document_question_answering.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/document_question_answering.md
new file mode 100644
index 0000000000000000000000000000000000000000..6c2d04f4ee859836401cf1e5d9c37c12c77f5827
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/document_question_answering.md
@@ -0,0 +1,476 @@
+
+
+# 문서 질의 응답(Document Question Answering) [[document_question_answering]]
+
+[[open-in-colab]]
+
+문서 시각적 질의 응답(Document Visual Question Answering)이라고도 하는
+문서 질의 응답(Document Question Answering)은 문서 이미지에 대한 질문에 답변을 주는 태스크입니다.
+이 태스크를 지원하는 모델의 입력은 일반적으로 이미지와 질문의 조합이고, 출력은 자연어로 된 답변입니다. 이러한 모델은 텍스트, 단어의 위치(바운딩 박스), 이미지 등 다양한 모달리티를 활용합니다.
+
+이 가이드는 다음 내용을 설명합니다:
+
+- [DocVQA dataset](https://huggingface.co/datasets/nielsr/docvqa_1200_examples_donut)을 사용해 [LayoutLMv2](../model_doc/layoutlmv2) 미세 조정하기
+- 추론을 위해 미세 조정된 모델을 사용하기
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/image-to-text)를 확인하는 것이 좋습니다.
+
+
+
+LayoutLMv2는 토큰의 마지막 은닉층 위에 질의 응답 헤드를 추가해 답변의 시작 토큰과 끝 토큰의 위치를 예측함으로써 문서 질의 응답 태스크를 해결합니다. 즉, 문맥이 주어졌을 때 질문에 답하는 정보를 추출하는 추출형 질의 응답(Extractive question answering)으로 문제를 처리합니다.
+문맥은 OCR 엔진의 출력에서 가져오며, 여기서는 Google의 Tesseract를 사용합니다.
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요. LayoutLMv2는 detectron2, torchvision 및 테서랙트를 필요로 합니다.
+
+```bash
+pip install -q transformers datasets
+```
+
+```bash
+pip install 'git+https://github.com/facebookresearch/detectron2.git'
+pip install torchvision
+```
+
+```bash
+sudo apt install tesseract-ocr
+pip install -q pytesseract
+```
+
+필요한 라이브러리들을 모두 설치한 후 런타임을 다시 시작합니다.
+
+커뮤니티에 당신의 모델을 공유하는 것을 권장합니다. Hugging Face 계정에 로그인해서 모델을 🤗 Hub에 업로드하세요.
+프롬프트가 실행되면, 로그인을 위해 토큰을 입력하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+몇 가지 전역 변수를 정의해 보겠습니다.
+
+```py
+>>> model_checkpoint = "microsoft/layoutlmv2-base-uncased"
+>>> batch_size = 4
+```
+
+## 데이터 불러오기 [[load-the-data]]
+
+이 가이드에서는 🤗 Hub에서 찾을 수 있는 전처리된 DocVQA의 작은 샘플을 사용합니다.
+DocVQA의 전체 데이터 세트를 사용하고 싶다면, [DocVQA homepage](https://rrc.cvc.uab.es/?ch=17)에 가입 후 다운로드 할 수 있습니다. 전체 데이터 세트를 다운로드 했다면, 이 가이드를 계속 진행하기 위해 [🤗 dataset에 파일을 가져오는 방법](https://huggingface.co/docs/datasets/loading#local-and-remote-files)을 확인하세요.
+
+```py
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("nielsr/docvqa_1200_examples")
+>>> dataset
+DatasetDict({
+ train: Dataset({
+ features: ['id', 'image', 'query', 'answers', 'words', 'bounding_boxes', 'answer'],
+ num_rows: 1000
+ })
+ test: Dataset({
+ features: ['id', 'image', 'query', 'answers', 'words', 'bounding_boxes', 'answer'],
+ num_rows: 200
+ })
+})
+```
+
+보시다시피, 데이터 세트는 이미 훈련 세트와 테스트 세트로 나누어져 있습니다. 무작위로 예제를 살펴보면서 특성을 확인해보세요.
+
+```py
+>>> dataset["train"].features
+```
+
+각 필드가 나타내는 내용은 다음과 같습니다:
+* `id`: 예제의 id
+* `image`: 문서 이미지를 포함하는 PIL.Image.Image 객체
+* `query`: 질문 문자열 - 여러 언어의 자연어로 된 질문
+* `answers`: 사람이 주석을 단 정답 리스트
+* `words` and `bounding_boxes`: OCR의 결과값들이며 이 가이드에서는 사용하지 않을 예정
+* `answer`: 다른 모델과 일치하는 답변이며 이 가이드에서는 사용하지 않을 예정
+
+영어로 된 질문만 남기고 다른 모델에 대한 예측을 포함하는 `answer` 특성을 삭제하겠습니다.
+그리고 주석 작성자가 제공한 데이터 세트에서 첫 번째 답변을 가져옵니다. 또는 무작위로 샘플을 추출할 수도 있습니다.
+
+```py
+>>> updated_dataset = dataset.map(lambda example: {"question": example["query"]["en"]}, remove_columns=["query"])
+>>> updated_dataset = updated_dataset.map(
+... lambda example: {"answer": example["answers"][0]}, remove_columns=["answer", "answers"]
+... )
+```
+
+이 가이드에서 사용하는 LayoutLMv2 체크포인트는 `max_position_embeddings = 512`로 훈련되었습니다(이 정보는 [체크포인트의 `config.json` 파일](https://huggingface.co/microsoft/layoutlmv2-base-uncased/blob/main/config.json#L18)에서 확인할 수 있습니다).
+바로 예제를 잘라낼 수도 있지만, 긴 문서의 끝에 답변이 있어 잘리는 상황을 피하기 위해 여기서는 임베딩이 512보다 길어질 가능성이 있는 몇 가지 예제를 제거하겠습니다.
+데이터 세트에 있는 대부분의 문서가 긴 경우 슬라이딩 윈도우 방법을 사용할 수 있습니다 - 자세한 내용을 확인하고 싶으면 이 [노트북](https://github.com/huggingface/notebooks/blob/main/examples/question_answering.ipynb)을 확인하세요.
+
+```py
+>>> updated_dataset = updated_dataset.filter(lambda x: len(x["words"]) + len(x["question"].split()) < 512)
+```
+
+이 시점에서 이 데이터 세트의 OCR 특성도 제거해 보겠습니다. OCR 특성은 다른 모델을 미세 조정하기 위한 것으로, 이 가이드에서 사용하는 모델의 입력 요구 사항과 일치하지 않기 때문에 이 특성을 사용하기 위해서는 일부 처리가 필요합니다.
+대신, 원본 데이터에 [`LayoutLMv2Processor`]를 사용하여 OCR 및 토큰화를 모두 수행할 수 있습니다.
+이렇게 하면 모델이 요구하는 입력을 얻을 수 있습니다.
+이미지를 수동으로 처리하려면, [`LayoutLMv2` model documentation](../model_doc/layoutlmv2)에서 모델이 요구하는 입력 포맷을 확인해보세요.
+
+```py
+>>> updated_dataset = updated_dataset.remove_columns("words")
+>>> updated_dataset = updated_dataset.remove_columns("bounding_boxes")
+```
+
+마지막으로, 데이터 탐색을 완료하기 위해 이미지 예시를 살펴봅시다.
+
+```py
+>>> updated_dataset["train"][11]["image"]
+```
+
+
+
+
+다음 예제를 비양자화된 버전의 모델 체크포인트로 실행하려면 최소 20GB의 GPU 메모리가 필요합니다.
+
+
+## 모델 로드[[loading-the-model]]
+
+모델을 90억 파라미터 버전의 체크포인트로 로드해 봅시다:
+
+```py
+>>> checkpoint = "HuggingFaceM4/idefics-9b"
+```
+
+다른 Transformers 모델과 마찬가지로, 체크포인트에서 프로세서와 모델 자체를 로드해야 합니다.
+IDEFICS 프로세서는 [`LlamaTokenizer`]와 IDEFICS 이미지 프로세서를 하나의 프로세서로 감싸서 텍스트와 이미지 입력을 모델에 맞게 준비합니다.
+
+```py
+>>> import torch
+
+>>> from transformers import IdeficsForVisionText2Text, AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained(checkpoint)
+
+>>> model = IdeficsForVisionText2Text.from_pretrained(checkpoint, torch_dtype=torch.bfloat16, device_map="auto")
+```
+
+`device_map`을 `"auto"`로 설정하면 사용 중인 장치를 고려하여 모델 가중치를 가장 최적화된 방식으로 로드하고 저장하는 방법을 자동으로 결정합니다.
+
+### 양자화된 모델[[quantized-model]]
+
+고용량 GPU 사용이 어려운 경우, 모델의 양자화된 버전을 로드할 수 있습니다. 모델과 프로세서를 4비트 정밀도로 로드하기 위해서, `from_pretrained` 메소드에 `BitsAndBytesConfig`를 전달하면 모델이 로드되는 동안 실시간으로 압축됩니다.
+
+```py
+>>> import torch
+>>> from transformers import IdeficsForVisionText2Text, AutoProcessor, BitsAndBytesConfig
+
+>>> quantization_config = BitsAndBytesConfig(
+... load_in_4bit=True,
+... bnb_4bit_compute_dtype=torch.float16,
+... )
+
+>>> processor = AutoProcessor.from_pretrained(checkpoint)
+
+>>> model = IdeficsForVisionText2Text.from_pretrained(
+... checkpoint,
+... quantization_config=quantization_config,
+... device_map="auto"
+... )
+```
+
+이제 모델을 제안된 방법 중 하나로 로드했으니, IDEFICS를 사용할 수 있는 작업들을 탐구해봅시다.
+
+## 이미지 캡셔닝[[image-captioning]]
+이미지 캡셔닝은 주어진 이미지에 대한 캡션을 예측하는 작업입니다. 일반적인 응용 분야는 시각 장애인이 다양한 상황을 탐색할 수 있도록 돕는 것입니다. 예를 들어, 온라인에서 이미지 콘텐츠를 탐색하는 데 도움을 줄 수 있습니다.
+
+작업을 설명하기 위해 캡션을 달 이미지 예시를 가져옵니다. 예시:
+
+
+
+
", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+A puppy in a flower bed
+```
+
+
+
+`max_new_tokens`의 크기를 증가시킬 때 발생할 수 있는 오류를 피하기 위해 `generate` 호출 시 `bad_words_ids`를 포함하는 것이 좋습니다. 모델로부터 생성된 이미지가 없을 때 새로운 `` 또는 `` 토큰을 생성하려고 하기 때문입니다.
+이 가이드에서처럼 `bad_words_ids`를 함수 호출 시에 매개변수로 설정하거나, [텍스트 생성 전략](../generation_strategies) 가이드에 설명된 대로 `GenerationConfig`에 저장할 수도 있습니다.
+
+
+## 프롬프트 이미지 캡셔닝[[prompted-image-captioning]]
+
+텍스트 프롬프트를 이용하여 이미지 캡셔닝을 확장할 수 있으며, 모델은 주어진 이미지를 바탕으로 텍스트를 계속 생성합니다. 다음 이미지를 예시로 들어보겠습니다:
+
+
+
+
", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+This is an image of the Eiffel Tower in Paris, France.
+```
+
+## 퓨샷 프롬프트[[few-shot-prompting]]
+
+IDEFICS는 훌륭한 제로샷 결과를 보여주지만, 작업에 특정 형식의 캡션이 필요하거나 작업의 복잡성을 높이는 다른 제한 사항이나 요구 사항이 있을 수 있습니다. 이럴 때 퓨샷 프롬프트를 사용하여 맥락 내 학습(In-Context Learning)을 가능하게 할 수 있습니다.
+프롬프트에 예시를 제공함으로써 모델이 주어진 예시의 형식을 모방한 결과를 생성하도록 유도할 수 있습니다.
+
+이전의 에펠탑 이미지를 모델에 예시로 사용하고, 모델에게 이미지의 객체를 학습하는 것 외에도 흥미로운 정보를 얻고 싶다는 것을 보여주는 프롬프트를 작성해 봅시다.
+그런 다음 자유의 여신상 이미지에 대해 동일한 응답 형식을 얻을 수 있는지 확인해 봅시다:
+
+
+
+
", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=30, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+User: Describe this image.
+Assistant: An image of the Eiffel Tower at night. Fun fact: the Eiffel Tower is the same height as an 81-storey building.
+User: Describe this image.
+Assistant: An image of the Statue of Liberty. Fun fact: the Statue of Liberty is 151 feet tall.
+```
+
+단 하나의 예시만으로도(즉, 1-shot) 모델이 작업 수행 방법을 학습했다는 점이 주목할 만합니다. 더 복잡한 작업의 경우, 더 많은 예시(예: 3-shot, 5-shot 등)를 사용하여 실험해 보는 것도 좋은 방법입니다.
+
+## 시각적 질의 응답[[visual-question-answering]]
+
+시각적 질의 응답(VQA)은 이미지를 기반으로 개방형 질문에 답하는 작업입니다. 이미지 캡셔닝과 마찬가지로 접근성 애플리케이션에서 사용할 수 있지만, 교육(시각 자료에 대한 추론), 고객 서비스(이미지를 기반으로 한 제품 질문), 이미지 검색 등에서도 사용할 수 있습니다.
+
+이 작업을 위해 새로운 이미지를 가져옵니다:
+
+
+
+
", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=20, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+Instruction: Provide an answer to the question. Use the image to answer.
+ Question: Where are these people and what's the weather like? Answer: They're in a park in New York City, and it's a beautiful day.
+```
+
+## 이미지 분류[[image-classification]]
+
+IDEFICS는 특정 카테고리의 라벨이 포함된 데이터로 명시적으로 학습되지 않아도 이미지를 다양한 카테고리로 분류할 수 있습니다. 카테고리 목록이 주어지면, 모델은 이미지와 텍스트 이해 능력을 사용하여 이미지가 속할 가능성이 높은 카테고리를 추론할 수 있습니다.
+
+여기에 야채 가판대 이미지가 있습니다.
+
+
+
+
", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=6, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+Instruction: Classify the following image into a single category from the following list: ['animals', 'vegetables', 'city landscape', 'cars', 'office'].
+Category: Vegetables
+```
+
+위 예제에서는 모델에게 이미지를 단일 카테고리로 분류하도록 지시했지만, 순위 분류를 하도록 모델에 프롬프트를 제공할 수도 있습니다.
+
+## 이미지 기반 텍스트 생성[[image-guided-text-generation]]
+
+이미지를 활용한 텍스트 생성 기술을 사용하면 더욱 창의적인 작업이 가능합니다. 이 기술은 이미지를 바탕으로 텍스트를 만들어내며, 제품 설명, 광고 문구, 장면 묘사 등 다양한 용도로 활용할 수 있습니다.
+
+간단한 예로, 빨간 문 이미지를 IDEFICS에 입력하여 이야기를 만들어보겠습니다:
+
+
+
+
", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, num_beams=2, max_new_tokens=200, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+Instruction: Use the image to write a story.
+ Story:
+Once upon a time, there was a little girl who lived in a house with a red door. She loved her red door. It was the prettiest door in the whole world.
+
+One day, the little girl was playing in her yard when she noticed a man standing on her doorstep. He was wearing a long black coat and a top hat.
+
+The little girl ran inside and told her mother about the man.
+
+Her mother said, “Don’t worry, honey. He’s just a friendly ghost.”
+
+The little girl wasn’t sure if she believed her mother, but she went outside anyway.
+
+When she got to the door, the man was gone.
+
+The next day, the little girl was playing in her yard again when she noticed the man standing on her doorstep.
+
+He was wearing a long black coat and a top hat.
+
+The little girl ran
+```
+
+IDEFICS가 문 앞에 있는 호박을 보고 유령에 대한 으스스한 할로윈 이야기를 만든 것 같습니다.
+
+
+
+이처럼 긴 텍스트를 생성할 때는 텍스트 생성 전략을 조정하는 것이 좋습니다. 이렇게 하면 생성된 결과물의 품질을 크게 향상시킬 수 있습니다. 자세한 내용은 [텍스트 생성 전략](../generation_strategies)을 참조하세요.
+
+
+## 배치 모드에서 추론 실행[[running-inference-in-batch-mode]]
+
+앞선 모든 섹션에서는 단일 예시에 대해 IDEFICS를 설명했습니다. 이와 매우 유사한 방식으로, 프롬프트 목록을 전달하여 여러 예시에 대한 추론을 실행할 수 있습니다:
+
+```py
+>>> prompts = [
+... [ "https://images.unsplash.com/photo-1543349689-9a4d426bee8e?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3501&q=80",
+... "This is an image of ",
+... ],
+... [ "https://images.unsplash.com/photo-1623944889288-cd147dbb517c?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "This is an image of ",
+... ],
+... [ "https://images.unsplash.com/photo-1471193945509-9ad0617afabf?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "This is an image of ",
+... ],
+... ]
+
+>>> inputs = processor(prompts, return_tensors="pt").to("cuda")
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> for i,t in enumerate(generated_text):
+... print(f"{i}:\n{t}\n")
+0:
+This is an image of the Eiffel Tower in Paris, France.
+
+1:
+This is an image of a couple on a picnic blanket.
+
+2:
+This is an image of a vegetable stand.
+```
+
+## 대화형 사용을 위한 IDEFICS 인스트럭트 실행[[idefics-instruct-for-conversational-use]]
+
+대화형 사용 사례를 위해, 🤗 Hub에서 명령어 수행에 최적화된 버전의 모델을 찾을 수 있습니다. 이곳에는 `HuggingFaceM4/idefics-80b-instruct`와 `HuggingFaceM4/idefics-9b-instruct`가 있습니다.
+
+이 체크포인트는 지도 학습 및 명령어 미세 조정 데이터셋의 혼합으로 각각의 기본 모델을 미세 조정한 결과입니다. 이를 통해 모델의 하위 작업 성능을 향상시키는 동시에 대화형 환경에서 모델을 더 사용하기 쉽게 합니다.
+
+대화형 사용을 위한 사용법 및 프롬프트는 기본 모델을 사용하는 것과 매우 유사합니다.
+
+```py
+>>> import torch
+>>> from transformers import IdeficsForVisionText2Text, AutoProcessor
+
+>>> device = "cuda" if torch.cuda.is_available() else "cpu"
+
+>>> checkpoint = "HuggingFaceM4/idefics-9b-instruct"
+>>> model = IdeficsForVisionText2Text.from_pretrained(checkpoint, torch_dtype=torch.bfloat16).to(device)
+>>> processor = AutoProcessor.from_pretrained(checkpoint)
+
+>>> prompts = [
+... [
+... "User: What is in this image?",
+... "https://upload.wikimedia.org/wikipedia/commons/8/86/Id%C3%A9fix.JPG",
+... "",
+
+... "\nAssistant: This picture depicts Idefix, the dog of Obelix in Asterix and Obelix. Idefix is running on the ground.",
+
+... "\nUser:",
+... "https://static.wikia.nocookie.net/asterix/images/2/25/R22b.gif/revision/latest?cb=20110815073052",
+... "And who is that?",
+
+... "\nAssistant:",
+... ],
+... ]
+
+>>> # --batched mode
+>>> inputs = processor(prompts, add_end_of_utterance_token=False, return_tensors="pt").to(device)
+>>> # --single sample mode
+>>> # inputs = processor(prompts[0], return_tensors="pt").to(device)
+
+>>> # args 생성
+>>> exit_condition = processor.tokenizer("", add_special_tokens=False).input_ids
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, eos_token_id=exit_condition, bad_words_ids=bad_words_ids, max_length=100)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> for i, t in enumerate(generated_text):
+... print(f"{i}:\n{t}\n")
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/image_captioning.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/image_captioning.md
new file mode 100644
index 0000000000000000000000000000000000000000..c4d0f99b6170ee067c49a2a6bf7734617bb5851f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/image_captioning.md
@@ -0,0 +1,281 @@
+
+
+
+# 이미지 캡셔닝[[image-captioning]]
+
+[[open-in-colab]]
+
+이미지 캡셔닝(Image captioning)은 주어진 이미지에 대한 캡션을 예측하는 작업입니다.
+이미지 캡셔닝은 시각 장애인이 다양한 상황을 탐색하는 데 도움을 줄 수 있도록 시각 장애인을 보조하는 등 실생활에서 흔히 활용됩니다.
+따라서 이미지 캡셔닝은 이미지를 설명함으로써 사람들의 콘텐츠 접근성을 개선하는 데 도움이 됩니다.
+
+이 가이드에서는 소개할 내용은 아래와 같습니다:
+
+* 이미지 캡셔닝 모델을 파인튜닝합니다.
+* 파인튜닝된 모델을 추론에 사용합니다.
+
+시작하기 전에 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate -q
+pip install jiwer -q
+```
+
+Hugging Face 계정에 로그인하면 모델을 업로드하고 커뮤니티에 공유할 수 있습니다.
+토큰을 입력하여 로그인하세요.
+
+
+```python
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+## 포켓몬 BLIP 캡션 데이터세트 가져오기[[load-the-pokmon-blip-captions-dataset]]
+
+{이미지-캡션} 쌍으로 구성된 데이터세트를 가져오려면 🤗 Dataset 라이브러리를 사용합니다.
+PyTorch에서 자신만의 이미지 캡션 데이터세트를 만들려면 [이 노트북](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/GIT/Fine_tune_GIT_on_an_image_captioning_dataset.ipynb)을 참조하세요.
+
+
+```python
+from datasets import load_dataset
+
+ds = load_dataset("lambdalabs/pokemon-blip-captions")
+ds
+```
+```bash
+DatasetDict({
+ train: Dataset({
+ features: ['image', 'text'],
+ num_rows: 833
+ })
+})
+```
+
+이 데이터세트는 `image`와 `text`라는 두 특성을 가지고 있습니다.
+
+
+
+많은 이미지 캡션 데이터세트에는 이미지당 여러 개의 캡션이 포함되어 있습니다.
+이러한 경우, 일반적으로 학습 중에 사용 가능한 캡션 중에서 무작위로 샘플을 추출합니다.
+
+
+
+[`~datasets.Dataset.train_test_split`] 메소드를 사용하여 데이터세트의 학습 분할을 학습 및 테스트 세트로 나눕니다:
+
+
+```python
+ds = ds["train"].train_test_split(test_size=0.1)
+train_ds = ds["train"]
+test_ds = ds["test"]
+```
+
+학습 세트의 샘플 몇 개를 시각화해 봅시다.
+Let's visualize a couple of samples from the training set.
+
+
+```python
+from textwrap import wrap
+import matplotlib.pyplot as plt
+import numpy as np
+
+
+def plot_images(images, captions):
+ plt.figure(figsize=(20, 20))
+ for i in range(len(images)):
+ ax = plt.subplot(1, len(images), i + 1)
+ caption = captions[i]
+ caption = "\n".join(wrap(caption, 12))
+ plt.title(caption)
+ plt.imshow(images[i])
+ plt.axis("off")
+
+
+sample_images_to_visualize = [np.array(train_ds[i]["image"]) for i in range(5)]
+sample_captions = [train_ds[i]["text"] for i in range(5)]
+plot_images(sample_images_to_visualize, sample_captions)
+```
+
+
+
+
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/image-classification)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에, 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+Hugging Face 계정에 로그인하여 모델을 업로드하고 커뮤니티에 공유하는 것을 권장합니다. 메시지가 표시되면, 토큰을 입력하여 로그인하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Food-101 데이터 세트 가져오기[[load-food101-dataset]]
+
+🤗 Datasets 라이브러리에서 Food-101 데이터 세트의 더 작은 부분 집합을 가져오는 것으로 시작합니다. 이렇게 하면 전체 데이터 세트에 대한
+훈련에 많은 시간을 할애하기 전에 실험을 통해 모든 것이 제대로 작동하는지 확인할 수 있습니다.
+
+```py
+>>> from datasets import load_dataset
+
+>>> food = load_dataset("food101", split="train[:5000]")
+```
+
+데이터 세트의 `train`을 [`~datasets.Dataset.train_test_split`] 메소드를 사용하여 훈련 및 테스트 세트로 분할하세요:
+
+```py
+>>> food = food.train_test_split(test_size=0.2)
+```
+
+그리고 예시를 살펴보세요:
+
+```py
+>>> food["train"][0]
+{'image': ,
+ 'label': 79}
+```
+
+데이터 세트의 각 예제에는 두 개의 필드가 있습니다:
+
+- `image`: 식품 항목의 PIL 이미지
+- `label`: 식품 항목의 레이블 클래스
+
+모델이 레이블 ID에서 레이블 이름을 쉽게 가져올 수 있도록
+레이블 이름을 정수로 매핑하고, 정수를 레이블 이름으로 매핑하는 사전을 만드세요:
+
+```py
+>>> labels = food["train"].features["label"].names
+>>> label2id, id2label = dict(), dict()
+>>> for i, label in enumerate(labels):
+... label2id[label] = str(i)
+... id2label[str(i)] = label
+```
+
+이제 레이블 ID를 레이블 이름으로 변환할 수 있습니다:
+
+```py
+>>> id2label[str(79)]
+'prime_rib'
+```
+
+## 전처리[[preprocess]]
+
+다음 단계는 이미지를 텐서로 처리하기 위해 ViT 이미지 프로세서를 가져오는 것입니다:
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> checkpoint = "google/vit-base-patch16-224-in21k"
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint)
+```
+
+
+
+이미지에 몇 가지 이미지 변환을 적용하여 과적합에 대해 모델을 더 견고하게 만듭니다. 여기서 Torchvision의 [`transforms`](https://pytorch.org/vision/stable/transforms.html) 모듈을 사용하지만, 원하는 이미지 라이브러리를 사용할 수도 있습니다.
+
+이미지의 임의 부분을 크롭하고 크기를 조정한 다음, 이미지 평균과 표준 편차로 정규화하세요:
+
+```py
+>>> from torchvision.transforms import RandomResizedCrop, Compose, Normalize, ToTensor
+
+>>> normalize = Normalize(mean=image_processor.image_mean, std=image_processor.image_std)
+>>> size = (
+... image_processor.size["shortest_edge"]
+... if "shortest_edge" in image_processor.size
+... else (image_processor.size["height"], image_processor.size["width"])
+... )
+>>> _transforms = Compose([RandomResizedCrop(size), ToTensor(), normalize])
+```
+
+그런 다음 전처리 함수를 만들어 변환을 적용하고 이미지의 `pixel_values`(모델에 대한 입력)를 반환하세요:
+
+```py
+>>> def transforms(examples):
+... examples["pixel_values"] = [_transforms(img.convert("RGB")) for img in examples["image"]]
+... del examples["image"]
+... return examples
+```
+
+전체 데이터 세트에 전처리 기능을 적용하려면 🤗 Datasets [`~datasets.Dataset.with_transform`]을 사용합니다. 데이터 세트의 요소를 가져올 때 변환이 즉시 적용됩니다:
+
+```py
+>>> food = food.with_transform(transforms)
+```
+
+이제 [`DefaultDataCollator`]를 사용하여 예제 배치를 만듭니다. 🤗 Transformers의 다른 데이터 콜레이터와 달리, `DefaultDataCollator`는 패딩과 같은 추가적인 전처리를 적용하지 않습니다.
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator()
+```
+
+
+
+
+
+
+
+과적합을 방지하고 모델을 보다 견고하게 만들기 위해 데이터 세트의 훈련 부분에 데이터 증강을 추가합니다.
+여기서 Keras 전처리 레이어로 훈련 데이터에 대한 변환(데이터 증강 포함)과
+검증 데이터에 대한 변환(중앙 크로핑, 크기 조정, 정규화만)을 정의합니다.
+`tf.image` 또는 다른 원하는 라이브러리를 사용할 수 있습니다.
+
+```py
+>>> from tensorflow import keras
+>>> from tensorflow.keras import layers
+
+>>> size = (image_processor.size["height"], image_processor.size["width"])
+
+>>> train_data_augmentation = keras.Sequential(
+... [
+... layers.RandomCrop(size[0], size[1]),
+... layers.Rescaling(scale=1.0 / 127.5, offset=-1),
+... layers.RandomFlip("horizontal"),
+... layers.RandomRotation(factor=0.02),
+... layers.RandomZoom(height_factor=0.2, width_factor=0.2),
+... ],
+... name="train_data_augmentation",
+... )
+
+>>> val_data_augmentation = keras.Sequential(
+... [
+... layers.CenterCrop(size[0], size[1]),
+... layers.Rescaling(scale=1.0 / 127.5, offset=-1),
+... ],
+... name="val_data_augmentation",
+... )
+```
+
+다음으로 한 번에 하나의 이미지가 아니라 이미지 배치에 적절한 변환을 적용하는 함수를 만듭니다.
+
+```py
+>>> import numpy as np
+>>> import tensorflow as tf
+>>> from PIL import Image
+
+
+>>> def convert_to_tf_tensor(image: Image):
+... np_image = np.array(image)
+... tf_image = tf.convert_to_tensor(np_image)
+... # `expand_dims()` is used to add a batch dimension since
+... # the TF augmentation layers operates on batched inputs.
+... return tf.expand_dims(tf_image, 0)
+
+
+>>> def preprocess_train(example_batch):
+... """Apply train_transforms across a batch."""
+... images = [
+... train_data_augmentation(convert_to_tf_tensor(image.convert("RGB"))) for image in example_batch["image"]
+... ]
+... example_batch["pixel_values"] = [tf.transpose(tf.squeeze(image)) for image in images]
+... return example_batch
+
+
+... def preprocess_val(example_batch):
+... """Apply val_transforms across a batch."""
+... images = [
+... val_data_augmentation(convert_to_tf_tensor(image.convert("RGB"))) for image in example_batch["image"]
+... ]
+... example_batch["pixel_values"] = [tf.transpose(tf.squeeze(image)) for image in images]
+... return example_batch
+```
+
+🤗 Datasets [`~datasets.Dataset.set_transform`]를 사용하여 즉시 변환을 적용하세요:
+
+```py
+food["train"].set_transform(preprocess_train)
+food["test"].set_transform(preprocess_val)
+```
+
+최종 전처리 단계로 `DefaultDataCollator`를 사용하여 예제 배치를 만듭니다. 🤗 Transformers의 다른 데이터 콜레이터와 달리
+`DefaultDataCollator`는 패딩과 같은 추가 전처리를 적용하지 않습니다.
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+```
+
+
+
+## 평가[[evaluate]]
+
+훈련 중에 평가 지표를 포함하면 모델의 성능을 평가하는 데 도움이 되는 경우가 많습니다.
+🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리로 평가 방법을 빠르게 가져올 수 있습니다. 이 작업에서는
+[accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) 평가 지표를 가져옵니다. (🤗 Evaluate [빠른 둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하여 평가 지표를 가져오고 계산하는 방법에 대해 자세히 알아보세요):
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+그런 다음 예측과 레이블을 [`~evaluate.EvaluationModule.compute`]에 전달하여 정확도를 계산하는 함수를 만듭니다:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... predictions = np.argmax(predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=labels)
+```
+
+이제 `compute_metrics` 함수를 사용할 준비가 되었으며, 훈련을 설정하면 이 함수로 되돌아올 것입니다.
+
+## 훈련[[train]]
+
+
+
+
+
+[`Trainer`]를 사용하여 모델을 미세 조정하는 방법에 익숙하지 않은 경우, [여기](../training#train-with-pytorch-trainer)에서 기본 튜토리얼을 확인하세요!
+
+
+
+이제 모델을 훈련시킬 준비가 되었습니다! [`AutoModelForImageClassification`]로 ViT를 가져옵니다. 예상되는 레이블 수, 레이블 매핑 및 레이블 수를 지정하세요:
+
+```py
+>>> from transformers import AutoModelForImageClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForImageClassification.from_pretrained(
+... checkpoint,
+... num_labels=len(labels),
+... id2label=id2label,
+... label2id=label2id,
+... )
+```
+
+이제 세 단계만 거치면 끝입니다:
+
+1. [`TrainingArguments`]에서 훈련 하이퍼파라미터를 정의하세요. `image` 열이 삭제되기 때문에 미사용 열을 제거하지 않는 것이 중요합니다. `image` 열이 없으면 `pixel_values`을 생성할 수 없습니다. 이 동작을 방지하려면 `remove_unused_columns=False`로 설정하세요! 다른 유일한 필수 매개변수는 모델 저장 위치를 지정하는 `output_dir`입니다. `push_to_hub=True`로 설정하면 이 모델을 허브에 푸시합니다(모델을 업로드하려면 Hugging Face에 로그인해야 합니다). 각 에폭이 끝날 때마다, [`Trainer`]가 정확도를 평가하고 훈련 체크포인트를 저장합니다.
+2. [`Trainer`]에 모델, 데이터 세트, 토크나이저, 데이터 콜레이터 및 `compute_metrics` 함수와 함께 훈련 인수를 전달하세요.
+3. [`~Trainer.train`]을 호출하여 모델을 미세 조정하세요.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_food_model",
+... remove_unused_columns=False,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... learning_rate=5e-5,
+... per_device_train_batch_size=16,
+... gradient_accumulation_steps=4,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... warmup_ratio=0.1,
+... logging_steps=10,
+... load_best_model_at_end=True,
+... metric_for_best_model="accuracy",
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... data_collator=data_collator,
+... train_dataset=food["train"],
+... eval_dataset=food["test"],
+... processing_class=image_processor,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면, 모든 사람이 모델을 사용할 수 있도록 [`~transformers.Trainer.push_to_hub`] 메소드로 모델을 허브에 공유하세요:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+
+
+
+Keras를 사용하여 모델을 미세 조정하는 방법에 익숙하지 않은 경우, 먼저 [기본 튜토리얼](./training#train-a-tensorflow-model-with-keras)을 확인하세요!
+
+
+
+TensorFlow에서 모델을 미세 조정하려면 다음 단계를 따르세요:
+1. 훈련 하이퍼파라미터를 정의하고 옵티마이저와 학습률 스케쥴을 설정합니다.
+2. 사전 훈련된 모델을 인스턴스화합니다.
+3. 🤗 Dataset을 `tf.data.Dataset`으로 변환합니다.
+4. 모델을 컴파일합니다.
+5. 콜백을 추가하고 훈련을 수행하기 위해 `fit()` 메소드를 사용합니다.
+6. 커뮤니티와 공유하기 위해 모델을 🤗 Hub에 업로드합니다.
+
+하이퍼파라미터, 옵티마이저 및 학습률 스케쥴을 정의하는 것으로 시작합니다:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_epochs = 5
+>>> num_train_steps = len(food["train"]) * num_epochs
+>>> learning_rate = 3e-5
+>>> weight_decay_rate = 0.01
+
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=learning_rate,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=weight_decay_rate,
+... num_warmup_steps=0,
+... )
+```
+
+그런 다음 레이블 매핑과 함께 [`TFAuto ModelForImageClassification`]으로 ViT를 가져옵니다:
+
+```py
+>>> from transformers import TFAutoModelForImageClassification
+
+>>> model = TFAutoModelForImageClassification.from_pretrained(
+... checkpoint,
+... id2label=id2label,
+... label2id=label2id,
+... )
+```
+
+데이터 세트를 [`~datasets.Dataset.to_tf_dataset`]와 `data_collator`를 사용하여 `tf.data.Dataset` 형식으로 변환하세요:
+
+```py
+>>> # converting our train dataset to tf.data.Dataset
+>>> tf_train_dataset = food["train"].to_tf_dataset(
+... columns="pixel_values", label_cols="label", shuffle=True, batch_size=batch_size, collate_fn=data_collator
+... )
+
+>>> # converting our test dataset to tf.data.Dataset
+>>> tf_eval_dataset = food["test"].to_tf_dataset(
+... columns="pixel_values", label_cols="label", shuffle=True, batch_size=batch_size, collate_fn=data_collator
+... )
+```
+
+`compile()`를 사용하여 훈련 모델을 구성하세요:
+
+```py
+>>> from tensorflow.keras.losses import SparseCategoricalCrossentropy
+
+>>> loss = tf.keras.losses.SparseCategoricalCrossentropy(from_logits=True)
+>>> model.compile(optimizer=optimizer, loss=loss)
+```
+
+예측에서 정확도를 계산하고 모델을 🤗 Hub로 푸시하려면 [Keras callbacks](../main_classes/keras_callbacks)를 사용하세요.
+`compute_metrics` 함수를 [KerasMetricCallback](../main_classes/keras_callbacks#transformers.KerasMetricCallback)에 전달하고,
+[PushToHubCallback](../main_classes/keras_callbacks#transformers.PushToHubCallback)을 사용하여 모델을 업로드합니다:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback, PushToHubCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_eval_dataset)
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="food_classifier",
+... tokenizer=image_processor,
+... save_strategy="no",
+... )
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+이제 모델을 훈련할 준비가 되었습니다! 훈련 및 검증 데이터 세트, 에폭 수와 함께 `fit()`을 호출하고,
+콜백을 사용하여 모델을 미세 조정합니다:
+
+```py
+>>> model.fit(tf_train_dataset, validation_data=tf_eval_dataset, epochs=num_epochs, callbacks=callbacks)
+Epoch 1/5
+250/250 [==============================] - 313s 1s/step - loss: 2.5623 - val_loss: 1.4161 - accuracy: 0.9290
+Epoch 2/5
+250/250 [==============================] - 265s 1s/step - loss: 0.9181 - val_loss: 0.6808 - accuracy: 0.9690
+Epoch 3/5
+250/250 [==============================] - 252s 1s/step - loss: 0.3910 - val_loss: 0.4303 - accuracy: 0.9820
+Epoch 4/5
+250/250 [==============================] - 251s 1s/step - loss: 0.2028 - val_loss: 0.3191 - accuracy: 0.9900
+Epoch 5/5
+250/250 [==============================] - 238s 949ms/step - loss: 0.1232 - val_loss: 0.3259 - accuracy: 0.9890
+```
+
+축하합니다! 모델을 미세 조정하고 🤗 Hub에 공유했습니다. 이제 추론에 사용할 수 있습니다!
+
+
+
+
+
+
+이미지 분류를 위한 모델을 미세 조정하는 자세한 예제는 다음 [PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb)을 참조하세요.
+
+
+
+## 추론[[inference]]
+
+좋아요, 이제 모델을 미세 조정했으니 추론에 사용할 수 있습니다!
+
+추론을 수행하고자 하는 이미지를 가져와봅시다:
+
+```py
+>>> ds = load_dataset("food101", split="validation[:10]")
+>>> image = ds["image"][0]
+```
+
+
+
+
+
+이미지를 전처리하기 위해 이미지 프로세서를 가져오고 `input`을 PyTorch 텐서로 반환합니다:
+
+```py
+>>> from transformers import AutoImageProcessor
+>>> import torch
+
+>>> image_processor = AutoImageProcessor.from_pretrained("my_awesome_food_model")
+>>> inputs = image_processor(image, return_tensors="pt")
+```
+
+입력을 모델에 전달하고 logits을 반환합니다:
+
+```py
+>>> from transformers import AutoModelForImageClassification
+
+>>> model = AutoModelForImageClassification.from_pretrained("my_awesome_food_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+확률이 가장 높은 예측 레이블을 가져오고, 모델의 `id2label` 매핑을 사용하여 레이블로 변환합니다:
+
+```py
+>>> predicted_label = logits.argmax(-1).item()
+>>> model.config.id2label[predicted_label]
+'beignets'
+```
+
+
+
+
+
+이미지를 전처리하기 위해 이미지 프로세서를 가져오고 `input`을 TensorFlow 텐서로 반환합니다:
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("MariaK/food_classifier")
+>>> inputs = image_processor(image, return_tensors="tf")
+```
+
+입력을 모델에 전달하고 logits을 반환합니다:
+
+```py
+>>> from transformers import TFAutoModelForImageClassification
+
+>>> model = TFAutoModelForImageClassification.from_pretrained("MariaK/food_classifier")
+>>> logits = model(**inputs).logits
+```
+
+확률이 가장 높은 예측 레이블을 가져오고, 모델의 `id2label` 매핑을 사용하여 레이블로 변환합니다:
+
+```py
+>>> predicted_class_id = int(tf.math.argmax(logits, axis=-1)[0])
+>>> model.config.id2label[predicted_class_id]
+'beignets'
+```
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/image_feature_extraction.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/image_feature_extraction.md
new file mode 100644
index 0000000000000000000000000000000000000000..965ea771100b5e73f55d9c03bfe9b1644d36f6bd
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/image_feature_extraction.md
@@ -0,0 +1,136 @@
+
+
+# 이미지 특징 추출[[image-feature-extraction]]
+
+[[open-in-colab]]
+
+이미지 특징 추출은 주어진 이미지에서 의미론적으로 의미 있는 특징을 추출하는 작업입니다. 이는 이미지 유사성 및 이미지 검색 등 다양한 사용 사례가 있습니다.
+게다가 대부분의 컴퓨터 비전 모델은 이미지 특징 추출에 사용할 수 있으며, 여기서 작업 특화 헤드(이미지 분류, 물체 감지 등)를 제거하고 특징을 얻을 수 있습니다. 이러한 특징은 가장자리 감지, 모서리 감지 등 고차원 수준에서 매우 유용합니다.
+또한 모델의 깊이에 따라 실제 세계에 대한 정보(예: 고양이가 어떻게 생겼는지)를 포함할 수도 있습니다. 따라서 이러한 출력은 특정 데이터 세트에 대한 새로운 분류기를 훈련하는 데 사용할 수 있습니다.
+
+이 가이드에서는:
+
+- `image-feature-extraction` 파이프라인을 활용하여 간단한 이미지 유사성 시스템을 구축하는 방법을 배웁니다.
+- 기본 모델 추론으로 동일한 작업을 수행합니다.
+
+## `image-feature-extraction` 파이프라인을 이용한 이미지 유사성[[image-similarity-using-image-feature-extraction-pipeline]]
+
+물고기 그물 위에 앉아 있는 두 장의 고양이 사진이 있습니다. 이 중 하나는 생성된 이미지입니다.
+
+```python
+from PIL import Image
+import requests
+
+img_urls = ["https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/cats.png", "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/cats.jpeg"]
+image_real = Image.open(requests.get(img_urls[0], stream=True).raw).convert("RGB")
+image_gen = Image.open(requests.get(img_urls[1], stream=True).raw).convert("RGB")
+```
+
+파이프라인을 실행해 봅시다. 먼저 파이프라인을 초기화하세요. 모델을 지정하지 않으면, 파이프라인은 자동으로 [google/vit-base-patch16-224](google/vit-base-patch16-224) 모델로 초기화됩니다. 유사도를 계산하려면 `pool`을 True로 설정하세요.
+
+
+```python
+import torch
+from transformers import pipeline
+
+DEVICE = torch.device('cuda' if torch.cuda.is_available() else 'cpu')
+pipe = pipeline(task="image-feature-extraction", model_name="google/vit-base-patch16-384", device=DEVICE, pool=True)
+```
+
+`pipe`를 사용하여 추론하려면 두 이미지를 모두 전달하세요.
+
+```python
+outputs = pipe([image_real, image_gen])
+```
+
+출력에는 두 이미지의 풀링된(pooled) 임베딩이 포함되어 있습니다.
+
+```python
+# 단일 출력의 길이 구하기
+print(len(outputs[0][0]))
+# 출력 결과 표시하기
+print(outputs)
+
+# 768
+# [[[-0.03909236937761307, 0.43381670117378235, -0.06913255900144577,
+```
+
+유사도 점수를 얻으려면, 이들을 유사도 함수에 전달해야 합니다.
+
+```python
+from torch.nn.functional import cosine_similarity
+
+similarity_score = cosine_similarity(torch.Tensor(outputs[0]),
+ torch.Tensor(outputs[1]), dim=1)
+
+print(similarity_score)
+
+# tensor([0.6043])
+```
+
+풀링 이전의 마지막 은닉 상태를 얻고 싶다면, `pool` 매개변수에 아무 값도 전달하지 마세요. 또한, 기본값은 `False`로 설정되어 있습니다. 이 은닉 상태는 모델의 특징을 기반으로 새로운 분류기나 모델을 훈련시키는 데 유용합니다.
+
+```python
+pipe = pipeline(task="image-feature-extraction", model_name="google/vit-base-patch16-224", device=DEVICE)
+output = pipe(image_real)
+```
+
+아직 출력이 풀링되지 않았기 때문에, 첫 번째 차원은 배치 크기이고 마지막 두 차원은 임베딩 형태인 마지막 은닉 상태를 얻을 수 있습니다.
+
+```python
+import numpy as np
+print(np.array(outputs).shape)
+# (1, 197, 768)
+```
+
+## `AutoModel`을 사용하여 특징과 유사성 얻기[[getting-features-and-similarities-using-automodel]]
+
+transformers의 `AutoModel` 클래스를 사용하여 특징을 얻을 수도 있습니다. `AutoModel`은 작업 특화 헤드 없이 모든 transformers 모델을 로드할 수 있으며, 이를 통해 특징을 추출할 수 있습니다.
+
+```python
+from transformers import AutoImageProcessor, AutoModel
+
+processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+model = AutoModel.from_pretrained("google/vit-base-patch16-224").to(DEVICE)
+```
+
+추론을 위한 간단한 함수를 작성해 보겠습니다. 먼저 입력값을 `processor`에 전달한 다음, 그 출력값을 `model`에 전달할 것입니다.
+
+```python
+def infer(image):
+ inputs = processor(image, return_tensors="pt").to(DEVICE)
+ outputs = model(**inputs)
+ return outputs.pooler_output
+```
+
+이 함수에 이미지를 직접 전달하여 임베딩을 얻을 수 있습니다.
+
+```python
+embed_real = infer(image_real)
+embed_gen = infer(image_gen)
+```
+
+그리고 이 임베딩을 사용하여 다시 유사도를 계산할 수 있습니다.
+
+```python
+from torch.nn.functional import cosine_similarity
+
+similarity_score = cosine_similarity(embed_real, embed_gen, dim=1)
+print(similarity_score)
+
+# tensor([0.6061], device='cuda:0', grad_fn=)
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/image_to_image.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/image_to_image.md
new file mode 100644
index 0000000000000000000000000000000000000000..f76122f78445055872188d382bec93cf3af75799
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/image_to_image.md
@@ -0,0 +1,132 @@
+
+
+# Image-to-Image 작업 가이드 [[image-to-image-task-guide]]
+
+[[open-in-colab]]
+
+Image-to-Image 작업은 애플리케이션이 이미지를 입력받아 또 다른 이미지를 출력하는 작업입니다. 여기에는 이미지 향상(초고해상도, 저조도 향상, 빗줄기 제거 등), 이미지 복원 등 다양한 하위 작업이 포함됩니다.
+
+이 가이드에서는 다음을 수행하는 방법을 보여줍니다.
+- 초고해상도 작업을 위한 image-to-image 파이프라인 사용,
+- 파이프라인 없이 동일한 작업을 위한 image-to-image 모델 실행
+
+이 가이드가 발표된 시점에서는, `image-to-image` 파이프라인은 초고해상도 작업만 지원한다는 점을 유의하세요.
+
+필요한 라이브러리를 설치하는 것부터 시작하겠습니다.
+
+```bash
+pip install transformers
+```
+
+이제 [Swin2SR 모델](https://huggingface.co/caidas/swin2SR-lightweight-x2-64)을 사용하여 파이프라인을 초기화할 수 있습니다. 그런 다음 이미지와 함께 호출하여 파이프라인으로 추론할 수 있습니다. 현재 이 파이프라인에서는 [Swin2SR 모델](https://huggingface.co/caidas/swin2SR-lightweight-x2-64)만 지원됩니다.
+
+```python
+from transformers import pipeline
+
+device = torch.device('cuda' if torch.cuda.is_available() else 'cpu')
+pipe = pipeline(task="image-to-image", model="caidas/swin2SR-lightweight-x2-64", device=device)
+```
+
+이제 이미지를 불러와 봅시다.
+
+```python
+from PIL import Image
+import requests
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/cat.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+print(image.size)
+```
+```bash
+# (532, 432)
+```
+
+
+
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/text-generation)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+커뮤니티에 모델을 업로드하고 공유하기 위해 Hugging Face 계정에 로그인하는 것을 권장합니다. 알림이 표시되면 토큰을 입력하여 로그인하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## ELI5 데이터 세트 불러오기[[load-eli5-dataset]]
+
+먼저, 🤗 Datasets 라이브러리에서 r/askscience의 작은 하위 집합인 ELI5 데이터 세트를 불러옵니다.
+이를 통해 전체 데이터 세트에서 학습하는 데 더 많은 시간을 투자하기 전에, 실험해봄으로써 모든 것이 작동하는지 확인할 수 있습니다.
+
+```py
+>>> from datasets import load_dataset
+
+>>> eli5 = load_dataset("eli5", split="train_asks[:5000]")
+```
+
+데이터 세트의 `train_asks` 분할을 [`~datasets.Dataset.train_test_split`] 메소드를 사용하여 학습 및 테스트 세트로 분할합니다:
+
+```py
+>>> eli5 = eli5.train_test_split(test_size=0.2)
+```
+
+그런 다음 예제를 살펴보세요:
+
+```py
+>>> eli5["train"][0]
+{'answers': {'a_id': ['c3d1aib', 'c3d4lya'],
+ 'score': [6, 3],
+ 'text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
+ "Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"]},
+ 'answers_urls': {'url': []},
+ 'document': '',
+ 'q_id': 'nyxfp',
+ 'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
+ 'selftext_urls': {'url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg']},
+ 'subreddit': 'askscience',
+ 'title': 'Few questions about this space walk photograph.',
+ 'title_urls': {'url': []}}
+```
+
+많아 보일 수 있지만, 실제로는 `text` 필드만 중요합니다. 언어 모델링 작업의 장점은 레이블이 필요하지 않다는 것입니다. 다음 단어 *자체가* 레이블입니다. (이렇게 레이블을 제공하지 않아도 되는 학습을 비지도 학습이라고 일컫습니다)
+
+## 전처리[[preprocess]]
+
+
+
+패딩 토큰으로 종결 토큰을 사용하고 `mlm=False`로 설정하세요. 이렇게 하면 입력을 오른쪽으로 한 칸씩 시프트한 값을 레이블로 사용합니다:
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> tokenizer.pad_token = tokenizer.eos_token
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False)
+```
+
+
+
+패딩 토큰으로 종결 토큰을 사용하고 `mlm=False`로 설정하세요. 이렇게 하면 입력을 오른쪽으로 한 칸씩 시프트한 값을 레이블로 사용합니다:
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False, return_tensors="tf")
+```
+
+
+
+
+
+## 훈련[[train]]
+
+
+
+
+
+[`Trainer`]를 사용하여 모델을 미세 조정하는 방법을 잘 모르신다면 [기본 튜토리얼](../training#train-with-pytorch-trainer)을 확인해보세요!
+
+
+
+이제 모델을 훈련하기 준비가 되었습니다! [`AutoModelForCausalLM`]를 사용하여 DistilGPT2를 불러옵니다:
+
+```py
+>>> from transformers import AutoModelForCausalLM, TrainingArguments, Trainer
+
+>>> model = AutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+```
+
+여기까지 진행하면 세 단계만 남았습니다:
+
+1. [`TrainingArguments`]에서 훈련 하이퍼파라미터를 정의하세요. `output_dir`은 유일한 필수 매개변수로, 모델을 저장할 위치를 지정합니다. (먼저 Hugging Face에 로그인 필수) `push_to_hub=True`로 설정하여 이 모델을 허브에 업로드할 수 있습니다.
+2. 훈련 인수를 [`Trainer`]에 모델, 데이터 세트 및 데이터 콜레이터와 함께 전달하세요.
+3. [`~Trainer.train`]을 호출하여 모델을 미세 조정하세요.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_eli5_clm-model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=lm_dataset["train"],
+... eval_dataset=lm_dataset["test"],
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면 [`~transformers.Trainer.evaluate`] 메소드를 사용하여 모델을 평가하고 퍼플렉서티를 얻을 수 있습니다:
+
+```py
+>>> import math
+
+>>> eval_results = trainer.evaluate()
+>>> print(f"Perplexity: {math.exp(eval_results['eval_loss']):.2f}")
+Perplexity: 49.61
+```
+
+그런 다음 [`~transformers.Trainer.push_to_hub`] 메소드를 사용하여 모델을 허브에 공유하세요. 이렇게 하면 누구나 모델을 사용할 수 있습니다:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras를 사용하여 모델을 미세 조정하는 방법에 익숙하지 않다면 [기본 튜토리얼](../training#train-a-tensorflow-model-with-keras)을 확인해보세요!
+
+
+TensorFlow에서 모델을 미세 조정하려면, 먼저 옵티마이저 함수, 학습률 스케줄 및 일부 훈련 하이퍼파라미터를 설정하세요:
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+그런 다음 [`TFAutoModelForCausalLM`]를 사용하여 DistilGPT2를 불러옵니다:
+
+```py
+>>> from transformers import TFAutoModelForCausalLM
+
+>>> model = TFAutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`]을 사용하여 데이터 세트를 `tf.data.Dataset` 형식으로 변환하세요:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... lm_dataset["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... lm_dataset["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method)을 사용하여 모델을 훈련하기 위해 구성하세요. Transformers 모델은 모두 기본적인 작업 관련 손실 함수를 가지고 있으므로, 원한다면 별도로 지정하지 않아도 됩니다:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # 별도로 loss 인자를 넣지 않았어요!
+```
+
+[`~transformers.PushToHubCallback`]에서 모델과 토크나이저를 업로드할 위치를 지정할 수 있습니다:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> callback = PushToHubCallback(
+... output_dir="my_awesome_eli5_clm-model",
+... tokenizer=tokenizer,
+... )
+```
+
+마지막으로, 모델을 훈련하기 위해 [`fit`](https://keras.io/api/models/model_training_apis/#fit-method)을 호출하세요. 훈련 데이터 세트, 검증 데이터 세트, 에폭 수 및 콜백을 전달하세요:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=[callback])
+```
+
+훈련이 완료되면 모델이 자동으로 허브에 업로드되어 모두가 사용할 수 있습니다!
+
+
+
+
+
+인과 언어 모델링을 위해 모델을 미세 조정하는 더 자세한 예제는 해당하는 [PyTorch 노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb) 또는 [TensorFlow 노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb)을 참조하세요.
+
+
+
+## 추론[[inference]]
+
+좋아요, 이제 모델을 미세 조정했으므로 추론에 사용할 수 있습니다!
+
+생성할 텍스트를 위한 프롬프트를 만들어보세요:
+
+```py
+>>> prompt = "Somatic hypermutation allows the immune system to"
+```
+
+추론을 위해 미세 조정된 모델을 간단히 사용하는 가장 간단한 방법은 [`pipeline`]에서 사용하는 것입니다. 모델과 함께 텍스트 생성을 위한 `pipeline`을 인스턴스화하고 텍스트를 전달하세요:
+
+```py
+>>> from transformers import pipeline
+
+>>> generator = pipeline("text-generation", model="my_awesome_eli5_clm-model")
+>>> generator(prompt)
+[{'generated_text': "Somatic hypermutation allows the immune system to be able to effectively reverse the damage caused by an infection.\n\n\nThe damage caused by an infection is caused by the immune system's ability to perform its own self-correcting tasks."}]
+```
+
+
+
+텍스트를 토큰화하고 `input_ids`를 PyTorch 텐서로 반환하세요:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_eli5_clm-model")
+>>> inputs = tokenizer(prompt, return_tensors="pt").input_ids
+```
+
+[`~generation.GenerationMixin.generate`] 메소드를 사용하여 텍스트를 생성하세요. 생성을 제어하는 다양한 텍스트 생성 전략과 매개변수에 대한 자세한 내용은 [텍스트 생성 전략](../generation_strategies) 페이지를 확인하세요.
+
+```py
+>>> from transformers import AutoModelForCausalLM
+
+>>> model = AutoModelForCausalLM.from_pretrained("my_awesome_eli5_clm-model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=True, top_k=50, top_p=0.95)
+```
+
+생성된 토큰 ID를 다시 텍스트로 디코딩하세요:
+
+```py
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+["Somatic hypermutation allows the immune system to react to drugs with the ability to adapt to a different environmental situation. In other words, a system of 'hypermutation' can help the immune system to adapt to a different environmental situation or in some cases even a single life. In contrast, researchers at the University of Massachusetts-Boston have found that 'hypermutation' is much stronger in mice than in humans but can be found in humans, and that it's not completely unknown to the immune system. A study on how the immune system"]
+```
+
+
+텍스트를 토큰화하고 `input_ids`를 TensorFlow 텐서로 반환하세요:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_eli5_clm-model")
+>>> inputs = tokenizer(prompt, return_tensors="tf").input_ids
+```
+
+[`~transformers.generation_tf_utils.TFGenerationMixin.generate`] 메소드를 사용하여 요약을 생성하세요. 생성을 제어하는 다양한 텍스트 생성 전략과 매개변수에 대한 자세한 내용은 [텍스트 생성 전략](../generation_strategies) 페이지를 확인하세요.
+
+```py
+>>> from transformers import TFAutoModelForCausalLM
+
+>>> model = TFAutoModelForCausalLM.from_pretrained("my_awesome_eli5_clm-model")
+>>> outputs = model.generate(input_ids=inputs, max_new_tokens=100, do_sample=True, top_k=50, top_p=0.95)
+```
+
+생성된 토큰 ID를 다시 텍스트로 디코딩하세요:
+
+```py
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Somatic hypermutation allows the immune system to detect the presence of other viruses as they become more prevalent. Therefore, researchers have identified a high proportion of human viruses. The proportion of virus-associated viruses in our study increases with age. Therefore, we propose a simple algorithm to detect the presence of these new viruses in our samples as a sign of improved immunity. A first study based on this algorithm, which will be published in Science on Friday, aims to show that this finding could translate into the development of a better vaccine that is more effective for']
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/mask_generation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/mask_generation.md
new file mode 100644
index 0000000000000000000000000000000000000000..7a937399391b7149b36a8f1d1374b3b30fc5e798
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/mask_generation.md
@@ -0,0 +1,228 @@
+
+
+# 마스크 생성[[mask-generation]]
+
+마스크 생성(Mask generation)은 이미지에 대한 의미 있는 마스크를 생성하는 작업입니다.
+이 작업은 [이미지 분할](semantic_segmentation)과 매우 유사하지만, 많은 차이점이 있습니다. 이미지 분할 모델은 라벨이 달린 데이터셋으로 학습되며, 학습 중에 본 클래스들로만 제한됩니다. 이미지가 주어지면, 이미지 분할 모델은 여러 마스크와 그에 해당하는 클래스를 반환합니다.
+
+반면, 마스크 생성 모델은 대량의 데이터로 학습되며 두 가지 모드로 작동합니다.
+- 프롬프트 모드(Prompting mode): 이 모드에서는 모델이 이미지와 프롬프트를 입력받습니다. 프롬프트는 이미지 내 객체의 2D 좌표(XY 좌표)나 객체를 둘러싼 바운딩 박스가 될 수 있습니다. 프롬프트 모드에서는 모델이 프롬프트가 가리키는 객체의 마스크만 반환합니다.
+- 전체 분할 모드(Segment Everything mode): 이 모드에서는 주어진 이미지 내에서 모든 마스크를 생성합니다. 이를 위해 그리드 형태의 점들을 생성하고 이를 이미지에 오버레이하여 추론합니다.
+
+마스크 생성 작업은 [전체 분할 모드(Segment Anything Model, SAM)](model_doc/sam)에 의해 지원됩니다. SAM은 Vision Transformer 기반 이미지 인코더, 프롬프트 인코더, 그리고 양방향 트랜스포머 마스크 디코더로 구성된 강력한 모델입니다. 이미지와 프롬프트는 인코딩되고, 디코더는 이러한 임베딩을 받아 유효한 마스크를 생성합니다.
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/fill-mask)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+Hugging Face 계정에 로그인하여 모델을 업로드하고 커뮤니티와의 공유를 권장합니다. 메시지가 표시되면(When prompted) 토큰을 입력하여 로그인합니다:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## ELI5 데이터 세트 가져오기[[load-eli5-dataset]]
+
+먼저 🤗 Datasets 라이브러리에서 ELI5 데이터 세트의 r/askscience 중 일부만 가져옵니다.
+이렇게 하면 전체 데이터 세트 학습에 더 많은 시간을 할애하기 전에 모든 것이 작동하는지 실험하고 확인할 수 있습니다.
+
+```py
+>>> from datasets import load_dataset
+
+>>> eli5 = load_dataset("eli5", split="train_asks[:5000]")
+```
+
+데이터 세트의 `train_asks`를 [`~datasets.Dataset.train_test_split`] 메소드를 사용해 훈련 데이터와 테스트 데이터로 분할합니다:
+
+```py
+>>> eli5 = eli5.train_test_split(test_size=0.2)
+```
+
+그리고 아래 예시를 살펴보세요:
+
+```py
+>>> eli5["train"][0]
+{'answers': {'a_id': ['c3d1aib', 'c3d4lya'],
+ 'score': [6, 3],
+ 'text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
+ "Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"]},
+ 'answers_urls': {'url': []},
+ 'document': '',
+ 'q_id': 'nyxfp',
+ 'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
+ 'selftext_urls': {'url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg']},
+ 'subreddit': 'askscience',
+ 'title': 'Few questions about this space walk photograph.',
+ 'title_urls': {'url': []}}
+```
+
+많아 보일 수 있지만 실제로는 `text` 필드에만 집중하면 됩나다.
+언어 모델링 작업의 멋진 점은 (비지도 학습으로) *다음 단어가 레이블*이기 때문에 레이블이 따로 필요하지 않습니다.
+
+## 전처리[[preprocess]]
+
+
+
+
+시퀀스 끝 토큰을 패딩 토큰으로 사용하고 데이터를 반복할 때마다 토큰을 무작위로 마스킹하도록 `mlm_-probability`를 지정합니다:
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> tokenizer.pad_token = tokenizer.eos_token
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=0.15)
+```
+
+
+
+시퀀스 끝 토큰을 패딩 토큰으로 사용하고 데이터를 반복할 때마다 토큰을 무작위로 마스킹하도록 `mlm_-probability`를 지정합니다:
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=0.15, return_tensors="tf")
+```
+
+
+
+## 훈련[[train]]
+
+
+
+
+
+[`Trainer`]로 모델을 미세 조정하는 데 익숙하지 않다면 기본 튜토리얼 [여기](../training#train-with-pytorch-trainer)를 살펴보세요!
+
+
+이제 모델 훈련을 시작할 준비가 되었습니다! [`AutoModelForMaskedLM`]를 사용해 DistilRoBERTa 모델을 가져옵니다:
+
+```py
+>>> from transformers import AutoModelForMaskedLM
+
+>>> model = AutoModelForMaskedLM.from_pretrained("distilbert/distilroberta-base")
+```
+
+이제 세 단계가 남았습니다:
+
+1. [`TrainingArguments`]의 훈련 하이퍼파라미터를 정의합니다. 모델 저장 위치를 지정하는 `output_dir`은 유일한 필수 파라미터입니다. `push_to_hub=True`를 설정하여 이 모델을 Hub에 업로드합니다 (모델을 업로드하려면 Hugging Face에 로그인해야 합니다).
+2. 모델, 데이터 세트 및 데이터 콜레이터(collator)와 함께 훈련 인수를 [`Trainer`]에 전달합니다.
+3. [`~Trainer.train`]을 호출하여 모델을 미세 조정합니다.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_eli5_mlm_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=lm_dataset["train"],
+... eval_dataset=lm_dataset["test"],
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면 [`~transformers.Trainer.evaluate`] 메소드를 사용하여 펄플렉서티(perplexity)를 계산하고 모델을 평가합니다:
+
+```py
+>>> import math
+
+>>> eval_results = trainer.evaluate()
+>>> print(f"Perplexity: {math.exp(eval_results['eval_loss']):.2f}")
+Perplexity: 8.76
+```
+
+그리고 [`~transformers.Trainer.push_to_hub`] 메소드를 사용해 다른 사람들이 사용할 수 있도록, Hub로 모델을 업로드합니다.
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras로 모델을 미세 조정하는 데 익숙하지 않다면 기본 튜토리얼 [여기](../training#train-a-tensorflow-model-with-keras)를 살펴보세요!
+
+
+TensorFlow로 모델을 미세 조정하기 위해서는 옵티마이저(optimizer) 함수 설정, 학습률(learning rate) 스케쥴링, 훈련 하이퍼파라미터 설정부터 시작하세요:
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+다음으로 [`TFAutoModelForMaskedLM`]를 사용해 DistilRoBERTa 모델을 가져옵니다:
+
+```py
+>>> from transformers import TFAutoModelForMaskedLM
+
+>>> model = TFAutoModelForMaskedLM.from_pretrained("distilbert/distilroberta-base")
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] 메소드를 사용해 데이터 세트를 `tf.data.Dataset` 형식으로 변환하세요:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... lm_dataset["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... lm_dataset["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) 메소드를 통해 모델 훈련을 구성합니다:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+이는 업로드할 모델과 토크나이저의 위치를 [`~transformers.PushToHubCallback`]에 지정하여 수행할 수 있습니다:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> callback = PushToHubCallback(
+... output_dir="my_awesome_eli5_mlm_model",
+... tokenizer=tokenizer,
+... )
+```
+
+드디어 모델을 훈련할 준비가 되었습니다!
+모델을 미세 조정할 때 훈련 및 검증 데이터 세트, 에포크 수, 콜백이 포함된 [`fit`](https://keras.io/api/models/model_training_apis/#fit-method)을 호출합니다:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=[callback])
+```
+
+훈련이 완료되면, 자동으로 Hub로 업로드되어 누구나 사용할 수 있습니다!
+
+
+
+
+
+마스킹된 언어 모델링을 위해 모델을 미세 조정하는 방법에 대한 보다 심층적인 예제는
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)
+또는 [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb)을 참조하세요.
+
+
+## 추론[[inference]]
+
+지금까지 모델 미세 조정을 잘 했으니, 추론에 사용할 수 있습니다!
+
+모델이 빈칸을 채울 텍스트를 스페셜 토큰(special token)인 `` 토큰으로 표시합니다:
+
+
+```py
+>>> text = "The Milky Way is a galaxy."
+```
+추론을 위해 미세 조정한 모델을 테스트하는 가장 간단한 방법은 [`pipeline`]에서 사용하는 것입니다.
+`fill-mask`태스크로 `pipeline`을 인스턴스화하고 텍스트를 전달합니다.
+`top_k` 매개변수를 사용하여 반환하는 예측의 수를 지정할 수 있습니다:
+
+```py
+>>> from transformers import pipeline
+
+>>> mask_filler = pipeline("fill-mask", "stevhliu/my_awesome_eli5_mlm_model")
+>>> mask_filler(text, top_k=3)
+[{'score': 0.5150994658470154,
+ 'token': 21300,
+ 'token_str': ' spiral',
+ 'sequence': 'The Milky Way is a spiral galaxy.'},
+ {'score': 0.07087188959121704,
+ 'token': 2232,
+ 'token_str': ' massive',
+ 'sequence': 'The Milky Way is a massive galaxy.'},
+ {'score': 0.06434620916843414,
+ 'token': 650,
+ 'token_str': ' small',
+ 'sequence': 'The Milky Way is a small galaxy.'}]
+```
+
+
+
+텍스트를 토큰화하고 `input_ids`를 PyTorch 텐서 형태로 반환합니다.
+또한, `` 토큰의 위치를 지정해야 합니다:
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_eli5_mlm_model")
+>>> inputs = tokenizer(text, return_tensors="pt")
+>>> mask_token_index = torch.where(inputs["input_ids"] == tokenizer.mask_token_id)[1]
+```
+
+모델에 `inputs`를 입력하고, 마스킹된 토큰의 `logits`를 반환합니다:
+
+```py
+>>> from transformers import AutoModelForMaskedLM
+
+>>> model = AutoModelForMaskedLM.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
+>>> logits = model(**inputs).logits
+>>> mask_token_logits = logits[0, mask_token_index, :]
+```
+
+그런 다음 가장 높은 확률은 가진 마스크 토큰 3개를 반환하고, 출력합니다:
+```py
+>>> top_3_tokens = torch.topk(mask_token_logits, 3, dim=1).indices[0].tolist()
+
+>>> for token in top_3_tokens:
+... print(text.replace(tokenizer.mask_token, tokenizer.decode([token])))
+The Milky Way is a spiral galaxy.
+The Milky Way is a massive galaxy.
+The Milky Way is a small galaxy.
+```
+
+
+텍스트를 토큰화하고 `input_ids`를 TensorFlow 텐서 형태로 반환합니다.
+또한, `` 토큰의 위치를 지정해야 합니다:
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_eli5_mlm_model")
+>>> inputs = tokenizer(text, return_tensors="tf")
+>>> mask_token_index = tf.where(inputs["input_ids"] == tokenizer.mask_token_id)[0, 1]
+```
+
+모델에 `inputs`를 입력하고, 마스킹된 토큰의 `logits`를 반환합니다:
+
+```py
+>>> from transformers import TFAutoModelForMaskedLM
+
+>>> model = TFAutoModelForMaskedLM.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
+>>> logits = model(**inputs).logits
+>>> mask_token_logits = logits[0, mask_token_index, :]
+```
+
+그런 다음 가장 높은 확률은 가진 마스크 토큰 3개를 반환하고, 출력합니다:
+```py
+>>> top_3_tokens = tf.math.top_k(mask_token_logits, 3).indices.numpy()
+
+>>> for token in top_3_tokens:
+... print(text.replace(tokenizer.mask_token, tokenizer.decode([token])))
+The Milky Way is a spiral galaxy.
+The Milky Way is a massive galaxy.
+The Milky Way is a small galaxy.
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/monocular_depth_estimation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/monocular_depth_estimation.md
new file mode 100644
index 0000000000000000000000000000000000000000..2c640d2a86db3d59e63111be73a314313e7aee08
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/monocular_depth_estimation.md
@@ -0,0 +1,144 @@
+
+
+# 단일 영상 기반 깊이 추정[[depth-estimation-pipeline]]
+
+단일 영상 기반 깊이 추정은 한 장면의 단일 이미지에서 장면의 깊이 정보를 예측하는 컴퓨터 비전 작업입니다.
+즉, 단일 카메라 시점의 장면에 있는 물체의 거리를 예측하는 과정입니다.
+
+단일 영상 기반 깊이 추정은 3D 재구성, 증강 현실, 자율 주행, 로봇 공학 등 다양한 분야에서 응용됩니다.
+조명 조건, 가려짐, 텍스처와 같은 요소의 영향을 받을 수 있는 장면 내 물체와 해당 깊이 정보 간의 복잡한 관계를 모델이 이해해야 하므로 까다로운 작업입니다.
+
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/depth-estimation)를 확인하는 것이 좋습니다.
+
+
+
+이번 가이드에서 배울 내용은 다음과 같습니다:
+
+* 깊이 추정 파이프라인 만들기
+* 직접 깊이 추정 추론하기
+
+시작하기 전에, 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install -q transformers
+```
+
+## 깊이 추정 파이프라인[[depth-estimation-inference-by-hand]]
+
+깊이 추정을 추론하는 가장 간단한 방법은 해당 기능을 제공하는 [`pipeline`]을 사용하는 것입니다.
+[Hugging Face Hub 체크포인트](https://huggingface.co/models?pipeline_tag=depth-estimation&sort=downloads)에서 파이프라인을 초기화합니다:
+
+```py
+>>> from transformers import pipeline
+
+>>> checkpoint = "vinvino02/glpn-nyu"
+>>> depth_estimator = pipeline("depth-estimation", model=checkpoint)
+```
+
+
+다음으로, 분석할 이미지를 한 장 선택하세요:
+
+```py
+>>> from PIL import Image
+>>> import requests
+
+>>> url = "https://unsplash.com/photos/HwBAsSbPBDU/download?ixid=MnwxMjA3fDB8MXxzZWFyY2h8MzR8fGNhciUyMGluJTIwdGhlJTIwc3RyZWV0fGVufDB8MHx8fDE2Nzg5MDEwODg&force=true&w=640"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> image
+```
+
+
+
+
+
+
+
+
+
+```py
+>>> from dataclasses import dataclass
+>>> from transformers.tokenization_utils_base import PreTrainedTokenizerBase, PaddingStrategy
+>>> from typing import Optional, Union
+>>> import torch
+
+
+>>> @dataclass
+... class DataCollatorForMultipleChoice:
+... """
+... Data collator that will dynamically pad the inputs for multiple choice received.
+... """
+
+... tokenizer: PreTrainedTokenizerBase
+... padding: Union[bool, str, PaddingStrategy] = True
+... max_length: Optional[int] = None
+... pad_to_multiple_of: Optional[int] = None
+
+... def __call__(self, features):
+... label_name = "label" if "label" in features[0].keys() else "labels"
+... labels = [feature.pop(label_name) for feature in features]
+... batch_size = len(features)
+... num_choices = len(features[0]["input_ids"])
+... flattened_features = [
+... [{k: v[i] for k, v in feature.items()} for i in range(num_choices)] for feature in features
+... ]
+... flattened_features = sum(flattened_features, [])
+
+... batch = self.tokenizer.pad(
+... flattened_features,
+... padding=self.padding,
+... max_length=self.max_length,
+... pad_to_multiple_of=self.pad_to_multiple_of,
+... return_tensors="pt",
+... )
+
+... batch = {k: v.view(batch_size, num_choices, -1) for k, v in batch.items()}
+... batch["labels"] = torch.tensor(labels, dtype=torch.int64)
+... return batch
+```
+
+
+```py
+>>> from dataclasses import dataclass
+>>> from transformers.tokenization_utils_base import PreTrainedTokenizerBase, PaddingStrategy
+>>> from typing import Optional, Union
+>>> import tensorflow as tf
+
+
+>>> @dataclass
+... class DataCollatorForMultipleChoice:
+... """
+... Data collator that will dynamically pad the inputs for multiple choice received.
+... """
+
+... tokenizer: PreTrainedTokenizerBase
+... padding: Union[bool, str, PaddingStrategy] = True
+... max_length: Optional[int] = None
+... pad_to_multiple_of: Optional[int] = None
+
+... def __call__(self, features):
+... label_name = "label" if "label" in features[0].keys() else "labels"
+... labels = [feature.pop(label_name) for feature in features]
+... batch_size = len(features)
+... num_choices = len(features[0]["input_ids"])
+... flattened_features = [
+... [{k: v[i] for k, v in feature.items()} for i in range(num_choices)] for feature in features
+... ]
+... flattened_features = sum(flattened_features, [])
+
+... batch = self.tokenizer.pad(
+... flattened_features,
+... padding=self.padding,
+... max_length=self.max_length,
+... pad_to_multiple_of=self.pad_to_multiple_of,
+... return_tensors="tf",
+... )
+
+... batch = {k: tf.reshape(v, (batch_size, num_choices, -1)) for k, v in batch.items()}
+... batch["labels"] = tf.convert_to_tensor(labels, dtype=tf.int64)
+... return batch
+```
+
+
+
+## 평가 하기[[evaluate]]
+
+훈련 중에 메트릭을 포함하면 모델의 성능을 평가하는 데 도움이 되는 경우가 많습니다. 🤗[Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리를 사용하여 평가 방법을 빠르게 가져올 수 있습니다. 이 작업에서는 [accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) 지표를 가져옵니다(🤗 Evaluate [둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하여 지표를 가져오고 계산하는 방법에 대해 자세히 알아보세요):
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+그리고 예측과 레이블을 [`~evaluate.EvaluationModule.compute`]에 전달하여 정확도를 계산하는 함수를 만듭니다:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... predictions = np.argmax(predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=labels)
+```
+
+이제 `compute_metrics` 함수를 사용할 준비가 되었으며, 훈련을 설정할 때 이 함수로 돌아가게 됩니다.
+
+## 훈련 하기[[train]]
+
+
+
+
+
+[`Trainer`]로 모델을 미세 조정하는 데 익숙하지 않다면 기본 튜토리얼 [여기](../training#train-with-pytorch-trainer)를 살펴보세요!
+
+
+
+이제 모델 훈련을 시작할 준비가 되었습니다! [`AutoModelForMultipleChoice`]로 BERT를 로드합니다:
+
+```py
+>>> from transformers import AutoModelForMultipleChoice, TrainingArguments, Trainer
+
+>>> model = AutoModelForMultipleChoice.from_pretrained("google-bert/bert-base-uncased")
+```
+
+이제 세 단계만 남았습니다:
+
+1. 훈련 하이퍼파라미터를 [`TrainingArguments`]에 정의합니다. 유일한 필수 매개변수는 모델을 저장할 위치를 지정하는 `output_dir`입니다. `push_to_hub=True`를 설정하여 이 모델을 허브에 푸시합니다(모델을 업로드하려면 허깅 페이스에 로그인해야 합니다). 각 에폭이 끝날 때마다 [`Trainer`]가 정확도를 평가하고 훈련 체크포인트를 저장합니다.
+2. 모델, 데이터 세트, 토크나이저, 데이터 콜레이터, `compute_metrics` 함수와 함께 훈련 인자를 [`Trainer`]에 전달합니다.
+3. [`~Trainer.train`]을 사용하여 모델을 미세 조정합니다.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_swag_model",
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... load_best_model_at_end=True,
+... learning_rate=5e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_swag["train"],
+... eval_dataset=tokenized_swag["validation"],
+... processing_class=tokenizer,
+... data_collator=DataCollatorForMultipleChoice(tokenizer=tokenizer),
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면 모든 사람이 모델을 사용할 수 있도록 [`~transformers.Trainer.push_to_hub`] 메소드를 사용하여 모델을 허브에 공유하세요:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras로 모델을 미세 조정하는 데 익숙하지 않다면 기본 튜토리얼 [여기](../training#train-a-tensorflow-model-with-keras)를 살펴보시기 바랍니다!
+
+
+TensorFlow에서 모델을 미세 조정하려면 최적화 함수, 학습률 스케쥴 및 몇 가지 학습 하이퍼파라미터를 설정하는 것부터 시작하세요:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_train_epochs = 2
+>>> total_train_steps = (len(tokenized_swag["train"]) // batch_size) * num_train_epochs
+>>> optimizer, schedule = create_optimizer(init_lr=5e-5, num_warmup_steps=0, num_train_steps=total_train_steps)
+```
+
+그리고 [`TFAutoModelForMultipleChoice`]로 BERT를 가져올 수 있습니다:
+
+```py
+>>> from transformers import TFAutoModelForMultipleChoice
+
+>>> model = TFAutoModelForMultipleChoice.from_pretrained("google-bert/bert-base-uncased")
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`]을 사용하여 데이터 세트를 `tf.data.Dataset` 형식으로 변환합니다:
+
+```py
+>>> data_collator = DataCollatorForMultipleChoice(tokenizer=tokenizer)
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_swag["train"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_swag["validation"],
+... shuffle=False,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method)을 사용하여 훈련 모델을 구성합니다:
+
+```py
+>>> model.compile(optimizer=optimizer)
+```
+
+훈련을 시작하기 전에 설정해야 할 마지막 두 가지는 예측의 정확도를 계산하고 모델을 허브로 푸시하는 방법을 제공하는 것입니다. 이 두 가지 작업은 모두 [Keras 콜백](../main_classes/keras_callbacks)을 사용하여 수행할 수 있습니다.
+
+`compute_metrics`함수를 [`~transformers.KerasMetricCallback`]에 전달하세요:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+모델과 토크나이저를 업로드할 위치를 [`~transformers.PushToHubCallback`]에서 지정하세요:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_model",
+... tokenizer=tokenizer,
+... )
+```
+
+그리고 콜백을 함께 묶습니다:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+이제 모델 훈련을 시작합니다! 훈련 및 검증 데이터 세트, 에폭 수, 콜백을 사용하여 [`fit`](https://keras.io/api/models/model_training_apis/#fit-method)을 호출하고 모델을 미세 조정합니다:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=2, callbacks=callbacks)
+```
+
+훈련이 완료되면 모델이 자동으로 허브에 업로드되어 누구나 사용할 수 있습니다!
+
+
+
+
+
+
+객관식 모델을 미세 조정하는 방법에 대한 보다 심층적인 예는 아래 문서를 참조하세요.
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice.ipynb)
+또는 [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice-tf.ipynb).
+
+
+
+## 추론 하기[[inference]]
+
+이제 모델을 미세 조정했으니 추론에 사용할 수 있습니다!
+
+텍스트와 두 개의 후보 답안을 작성합니다:
+
+```py
+>>> prompt = "France has a bread law, Le Décret Pain, with strict rules on what is allowed in a traditional baguette."
+>>> candidate1 = "The law does not apply to croissants and brioche."
+>>> candidate2 = "The law applies to baguettes."
+```
+
+
+
+각 프롬프트와 후보 답변 쌍을 토큰화하여 PyTorch 텐서를 반환합니다. 또한 `labels`을 생성해야 합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_swag_model")
+>>> inputs = tokenizer([[prompt, candidate1], [prompt, candidate2]], return_tensors="pt", padding=True)
+>>> labels = torch.tensor(0).unsqueeze(0)
+```
+
+입력과 레이블을 모델에 전달하고 `logits`을 반환합니다:
+
+```py
+>>> from transformers import AutoModelForMultipleChoice
+
+>>> model = AutoModelForMultipleChoice.from_pretrained("my_awesome_swag_model")
+>>> outputs = model(**{k: v.unsqueeze(0) for k, v in inputs.items()}, labels=labels)
+>>> logits = outputs.logits
+```
+
+가장 높은 확률을 가진 클래스를 가져옵니다:
+
+```py
+>>> predicted_class = logits.argmax().item()
+>>> predicted_class
+'0'
+```
+
+
+각 프롬프트와 후보 답안 쌍을 토큰화하여 텐서플로 텐서를 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_swag_model")
+>>> inputs = tokenizer([[prompt, candidate1], [prompt, candidate2]], return_tensors="tf", padding=True)
+```
+
+모델에 입력을 전달하고 `logits`를 반환합니다:
+
+```py
+>>> from transformers import TFAutoModelForMultipleChoice
+
+>>> model = TFAutoModelForMultipleChoice.from_pretrained("my_awesome_swag_model")
+>>> inputs = {k: tf.expand_dims(v, 0) for k, v in inputs.items()}
+>>> outputs = model(inputs)
+>>> logits = outputs.logits
+```
+
+가장 높은 확률을 가진 클래스를 가져옵니다:
+
+```py
+>>> predicted_class = int(tf.math.argmax(logits, axis=-1)[0])
+>>> predicted_class
+'0'
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/object_detection.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/object_detection.md
new file mode 100644
index 0000000000000000000000000000000000000000..e027ad65a9ada8c07b0af7403cf62d1e31f37099
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/object_detection.md
@@ -0,0 +1,583 @@
+
+
+# 객체 탐지 [[object-detection]]
+
+[[open-in-colab]]
+
+객체 탐지는 이미지에서 인스턴스(예: 사람, 건물 또는 자동차)를 감지하는 컴퓨터 비전 작업입니다. 객체 탐지 모델은 이미지를 입력으로 받고 탐지된 바운딩 박스의 좌표와 관련된 레이블을 출력합니다.
+하나의 이미지에는 여러 객체가 있을 수 있으며 각각은 자체적인 바운딩 박스와 레이블을 가질 수 있습니다(예: 차와 건물이 있는 이미지).
+또한 각 객체는 이미지의 다른 부분에 존재할 수 있습니다(예: 이미지에 여러 대의 차가 있을 수 있음).
+이 작업은 보행자, 도로 표지판, 신호등과 같은 것들을 감지하는 자율 주행에 일반적으로 사용됩니다.
+다른 응용 분야로는 이미지 내 객체 수 계산 및 이미지 검색 등이 있습니다.
+
+이 가이드에서 다음을 배울 것입니다:
+
+ 1. 합성곱 백본(인풋 데이터의 특성을 추출하는 합성곱 네트워크)과 인코더-디코더 트랜스포머 모델을 결합한 [DETR](https://huggingface.co/docs/transformers/model_doc/detr) 모델을 [CPPE-5](https://huggingface.co/datasets/cppe-5) 데이터 세트에 대해 미세조정 하기
+ 2. 미세조정 한 모델을 추론에 사용하기.
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/object-detection)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+```bash
+pip install -q datasets transformers evaluate timm albumentations
+```
+
+허깅페이스 허브에서 데이터 세트를 가져오기 위한 🤗 Datasets과 모델을 학습하기 위한 🤗 Transformers, 데이터를 증강하기 위한 `albumentations`를 사용합니다.
+DETR 모델의 합성곱 백본을 가져오기 위해서는 현재 `timm`이 필요합니다.
+
+커뮤니티에 모델을 업로드하고 공유할 수 있도록 Hugging Face 계정에 로그인하는 것을 권장합니다. 프롬프트가 나타나면 토큰을 입력하여 로그인하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## CPPE-5 데이터 세트 가져오기 [[load-the-CPPE-5-dataset]]
+
+[CPPE-5](https://huggingface.co/datasets/cppe-5) 데이터 세트는 COVID-19 대유행 상황에서 의료 전문인력 보호 장비(PPE)를 식별하는 어노테이션이 포함된 이미지를 담고 있습니다.
+
+데이터 세트를 가져오세요:
+
+```py
+>>> from datasets import load_dataset
+
+>>> cppe5 = load_dataset("cppe-5")
+>>> cppe5
+DatasetDict({
+ train: Dataset({
+ features: ['image_id', 'image', 'width', 'height', 'objects'],
+ num_rows: 1000
+ })
+ test: Dataset({
+ features: ['image_id', 'image', 'width', 'height', 'objects'],
+ num_rows: 29
+ })
+})
+```
+
+이 데이터 세트는 학습 세트 이미지 1,000개와 테스트 세트 이미지 29개를 갖고 있습니다.
+
+데이터에 익숙해지기 위해, 예시가 어떻게 구성되어 있는지 살펴보세요.
+
+```py
+>>> cppe5["train"][0]
+{'image_id': 15,
+ 'image': ,
+ 'width': 943,
+ 'height': 663,
+ 'objects': {'id': [114, 115, 116, 117],
+ 'area': [3796, 1596, 152768, 81002],
+ 'bbox': [[302.0, 109.0, 73.0, 52.0],
+ [810.0, 100.0, 57.0, 28.0],
+ [160.0, 31.0, 248.0, 616.0],
+ [741.0, 68.0, 202.0, 401.0]],
+ 'category': [4, 4, 0, 0]}}
+```
+
+데이터 세트에 있는 예시는 다음의 영역을 가지고 있습니다:
+
+- `image_id`: 예시 이미지 id
+- `image`: 이미지를 포함하는 `PIL.Image.Image` 객체
+- `width`: 이미지의 너비
+- `height`: 이미지의 높이
+- `objects`: 이미지 안의 객체들의 바운딩 박스 메타데이터를 포함하는 딕셔너리:
+ - `id`: 어노테이션 id
+ - `area`: 바운딩 박스의 면적
+ - `bbox`: 객체의 바운딩 박스 ([COCO 포맷](https://albumentations.ai/docs/getting_started/bounding_boxes_augmentation/#coco)으로)
+ - `category`: 객체의 카테고리, 가능한 값으로는 `Coverall (0)`, `Face_Shield (1)`, `Gloves (2)`, `Goggles (3)` 및 `Mask (4)` 가 포함됩니다.
+
+`bbox` 필드가 DETR 모델이 요구하는 COCO 형식을 따른다는 것을 알 수 있습니다.
+그러나 `objects` 내부의 필드 그룹은 DETR이 요구하는 어노테이션 형식과 다릅니다. 따라서 이 데이터를 학습에 사용하기 전에 전처리를 적용해야 합니다.
+
+데이터를 더 잘 이해하기 위해서 데이터 세트에서 한 가지 예시를 시각화하세요.
+
+```py
+>>> import numpy as np
+>>> import os
+>>> from PIL import Image, ImageDraw
+
+>>> image = cppe5["train"][0]["image"]
+>>> annotations = cppe5["train"][0]["objects"]
+>>> draw = ImageDraw.Draw(image)
+
+>>> categories = cppe5["train"].features["objects"].feature["category"].names
+
+>>> id2label = {index: x for index, x in enumerate(categories, start=0)}
+>>> label2id = {v: k for k, v in id2label.items()}
+
+>>> for i in range(len(annotations["id"])):
+... box = annotations["bbox"][i - 1]
+... class_idx = annotations["category"][i - 1]
+... x, y, w, h = tuple(box)
+... draw.rectangle((x, y, x + w, y + h), outline="red", width=1)
+... draw.text((x, y), id2label[class_idx], fill="white")
+
+>>> image
+```
+
+
+
+
COCO-스타일 지표 로 평가됩니다.
+기존에 구현된 평가 지표 중 하나를 사용할 수도 있지만, 여기에서는 허깅페이스 허브에 푸시한 최종 모델을 평가하는 데 `torchvision`에서 제공하는 평가 지표를 사용합니다.
+
+`torchvision` 평가자(evaluator)를 사용하려면 실측값인 COCO 데이터 세트를 준비해야 합니다.
+COCO 데이터 세트를 빌드하는 API는 데이터를 특정 형식으로 저장해야 하므로, 먼저 이미지와 어노테이션을 디스크에 저장해야 합니다.
+학습을 위해 데이터를 준비할 때와 마찬가지로, cppe5["test"]에서의 어노테이션은 포맷을 맞춰야 합니다. 그러나 이미지는 그대로 유지해야 합니다.
+
+평가 단계는 약간의 작업이 필요하지만, 크게 세 가지 주요 단계로 나눌 수 있습니다.
+먼저, `cppe5["test"]` 세트를 준비합니다: 어노테이션을 포맷에 맞게 만들고 데이터를 디스크에 저장합니다.
+
+```py
+>>> import json
+
+
+>>> # format annotations the same as for training, no need for data augmentation
+>>> def val_formatted_anns(image_id, objects):
+... annotations = []
+... for i in range(0, len(objects["id"])):
+... new_ann = {
+... "id": objects["id"][i],
+... "category_id": objects["category"][i],
+... "iscrowd": 0,
+... "image_id": image_id,
+... "area": objects["area"][i],
+... "bbox": objects["bbox"][i],
+... }
+... annotations.append(new_ann)
+
+... return annotations
+
+
+>>> # Save images and annotations into the files torchvision.datasets.CocoDetection expects
+>>> def save_cppe5_annotation_file_images(cppe5):
+... output_json = {}
+... path_output_cppe5 = f"{os.getcwd()}/cppe5/"
+
+... if not os.path.exists(path_output_cppe5):
+... os.makedirs(path_output_cppe5)
+
+... path_anno = os.path.join(path_output_cppe5, "cppe5_ann.json")
+... categories_json = [{"supercategory": "none", "id": id, "name": id2label[id]} for id in id2label]
+... output_json["images"] = []
+... output_json["annotations"] = []
+... for example in cppe5:
+... ann = val_formatted_anns(example["image_id"], example["objects"])
+... output_json["images"].append(
+... {
+... "id": example["image_id"],
+... "width": example["image"].width,
+... "height": example["image"].height,
+... "file_name": f"{example['image_id']}.png",
+... }
+... )
+... output_json["annotations"].extend(ann)
+... output_json["categories"] = categories_json
+
+... with open(path_anno, "w") as file:
+... json.dump(output_json, file, ensure_ascii=False, indent=4)
+
+... for im, img_id in zip(cppe5["image"], cppe5["image_id"]):
+... path_img = os.path.join(path_output_cppe5, f"{img_id}.png")
+... im.save(path_img)
+
+... return path_output_cppe5, path_anno
+```
+
+다음으로, `cocoevaluator`와 함께 사용할 수 있는 `CocoDetection` 클래스의 인스턴스를 준비합니다.
+
+```py
+>>> import torchvision
+
+
+>>> class CocoDetection(torchvision.datasets.CocoDetection):
+... def __init__(self, img_folder, image_processor, ann_file):
+... super().__init__(img_folder, ann_file)
+... self.image_processor = image_processor
+
+... def __getitem__(self, idx):
+... # read in PIL image and target in COCO format
+... img, target = super(CocoDetection, self).__getitem__(idx)
+
+... # preprocess image and target: converting target to DETR format,
+... # resizing + normalization of both image and target)
+... image_id = self.ids[idx]
+... target = {"image_id": image_id, "annotations": target}
+... encoding = self.image_processor(images=img, annotations=target, return_tensors="pt")
+... pixel_values = encoding["pixel_values"].squeeze() # remove batch dimension
+... target = encoding["labels"][0] # remove batch dimension
+
+... return {"pixel_values": pixel_values, "labels": target}
+
+
+>>> im_processor = AutoImageProcessor.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
+
+>>> path_output_cppe5, path_anno = save_cppe5_annotation_file_images(cppe5["test"])
+>>> test_ds_coco_format = CocoDetection(path_output_cppe5, im_processor, path_anno)
+```
+
+마지막으로, 평가 지표를 가져와서 평가를 실행합니다.
+
+```py
+>>> import evaluate
+>>> from tqdm import tqdm
+
+>>> model = AutoModelForObjectDetection.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
+>>> module = evaluate.load("ybelkada/cocoevaluate", coco=test_ds_coco_format.coco)
+>>> val_dataloader = torch.utils.data.DataLoader(
+... test_ds_coco_format, batch_size=8, shuffle=False, num_workers=4, collate_fn=collate_fn
+... )
+
+>>> with torch.no_grad():
+... for idx, batch in enumerate(tqdm(val_dataloader)):
+... pixel_values = batch["pixel_values"]
+... pixel_mask = batch["pixel_mask"]
+
+... labels = [
+... {k: v for k, v in t.items()} for t in batch["labels"]
+... ] # these are in DETR format, resized + normalized
+
+... # forward pass
+... outputs = model(pixel_values=pixel_values, pixel_mask=pixel_mask)
+
+... orig_target_sizes = torch.stack([target["orig_size"] for target in labels], dim=0)
+... results = im_processor.post_process(outputs, orig_target_sizes) # convert outputs of model to Pascal VOC format (xmin, ymin, xmax, ymax)
+
+... module.add(prediction=results, reference=labels)
+... del batch
+
+>>> results = module.compute()
+>>> print(results)
+Accumulating evaluation results...
+DONE (t=0.08s).
+IoU metric: bbox
+ Average Precision (AP) @[ IoU=0.50:0.95 | area= all | maxDets=100 ] = 0.352
+ Average Precision (AP) @[ IoU=0.50 | area= all | maxDets=100 ] = 0.681
+ Average Precision (AP) @[ IoU=0.75 | area= all | maxDets=100 ] = 0.292
+ Average Precision (AP) @[ IoU=0.50:0.95 | area= small | maxDets=100 ] = 0.168
+ Average Precision (AP) @[ IoU=0.50:0.95 | area=medium | maxDets=100 ] = 0.208
+ Average Precision (AP) @[ IoU=0.50:0.95 | area= large | maxDets=100 ] = 0.429
+ Average Recall (AR) @[ IoU=0.50:0.95 | area= all | maxDets= 1 ] = 0.274
+ Average Recall (AR) @[ IoU=0.50:0.95 | area= all | maxDets= 10 ] = 0.484
+ Average Recall (AR) @[ IoU=0.50:0.95 | area= all | maxDets=100 ] = 0.501
+ Average Recall (AR) @[ IoU=0.50:0.95 | area= small | maxDets=100 ] = 0.191
+ Average Recall (AR) @[ IoU=0.50:0.95 | area=medium | maxDets=100 ] = 0.323
+ Average Recall (AR) @[ IoU=0.50:0.95 | area= large | maxDets=100 ] = 0.590
+```
+
+이러한 결과는 [`~transformers.TrainingArguments`]의 하이퍼파라미터를 조정하여 더욱 개선될 수 있습니다. 한번 시도해 보세요!
+
+## 추론하기 [[inference]]
+
+DETR 모델을 미세 조정 및 평가하고, 허깅페이스 허브에 업로드 했으므로 추론에 사용할 수 있습니다.
+
+미세 조정된 모델을 추론에 사용하는 가장 간단한 방법은 [`pipeline`]에서 모델을 사용하는 것입니다.
+모델과 함께 객체 탐지를 위한 파이프라인을 인스턴스화하고, 이미지를 전달하세요:
+
+```py
+>>> from transformers import pipeline
+>>> import requests
+
+>>> url = "https://i.imgur.com/2lnWoly.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> obj_detector = pipeline("object-detection", model="devonho/detr-resnet-50_finetuned_cppe5")
+>>> obj_detector(image)
+```
+
+만약 원한다면 수동으로 `pipeline`의 결과를 재현할 수 있습니다:
+
+```py
+>>> image_processor = AutoImageProcessor.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
+>>> model = AutoModelForObjectDetection.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
+
+>>> with torch.no_grad():
+... inputs = image_processor(images=image, return_tensors="pt")
+... outputs = model(**inputs)
+... target_sizes = torch.tensor([image.size[::-1]])
+... results = image_processor.post_process_object_detection(outputs, threshold=0.5, target_sizes=target_sizes)[0]
+
+>>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
+... box = [round(i, 2) for i in box.tolist()]
+... print(
+... f"Detected {model.config.id2label[label.item()]} with confidence "
+... f"{round(score.item(), 3)} at location {box}"
+... )
+Detected Coverall with confidence 0.566 at location [1215.32, 147.38, 4401.81, 3227.08]
+Detected Mask with confidence 0.584 at location [2449.06, 823.19, 3256.43, 1413.9]
+```
+
+결과를 시각화하겠습니다:
+```py
+>>> draw = ImageDraw.Draw(image)
+
+>>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
+... box = [round(i, 2) for i in box.tolist()]
+... x, y, x2, y2 = tuple(box)
+... draw.rectangle((x, y, x2, y2), outline="red", width=1)
+... draw.text((x, y), model.config.id2label[label.item()], fill="white")
+
+>>> image
+```
+
+
+
+
+
+프롬프트 엔지니어링은 대규모 언어 모델 출력 최적화 과정의 일부일 뿐입니다. 또 다른 중요한 구성 요소는 최적의 텍스트 생성 전략을 선택하는 것입니다. 학습 가능한 매개변수를 수정하지 않고도 대규모 언어 모델이 텍스트를 생성하리 때 각각의 후속 토큰을 선택하는 방식을 사용자가 직접 정의할 수 있습니다. 텍스트 생성 매개변수를 조정함으로써 생성된 텍스트의 반복을 줄이고 더 일관되고 사람이 말하는 것 같은 텍스트를 만들 수 있습니다. 텍스트 생성 전략과 매개변수는 이 가이드의 범위를 벗어나지만, 다음 가이드에서 이러한 주제에 대해 자세히 알아볼 수 있습니다:
+
+* [대규모 언어 모델을 이용한 생성](../llm_tutorial)
+* [텍스트 생성 전략](../generation_strategies)
+
+
+
+## 프롬프팅의 기초 [[basics-of-prompting]]
+
+### 모델의 유형 [[types-of-models]]
+
+현대의 대부분의 대규모 언어 모델은 디코더만을 이용한 트랜스포머입니다. 예를 들어 [LLaMA](../model_doc/llama),
+[Llama2](../model_doc/llama2), [Falcon](../model_doc/falcon), [GPT2](../model_doc/gpt2) 등이 있습니다. 그러나 [Flan-T5](../model_doc/flan-t5)와 [BART](../model_doc/bart)와 같은 인코더-디코더 기반의 트랜스포머 대규모 언어 모델을 접할 수도 있습니다.
+
+인코더-디코더 기반의 모델은 일반적으로 출력이 입력에 **크게** 의존하는 생성 작업에 사용됩니다. 예를 들어, 번역과 요약 작업에 사용됩니다. 디코더 전용 모델은 다른 모든 유형의 생성 작업에 사용됩니다.
+
+파이프라인을 사용하여 대규모 언어 모델으로 텍스트를 생성할 때, 어떤 유형의 대규모 언어 모델을 사용하고 있는지 아는 것이 중요합니다. 왜냐하면 이들은 서로 다른 파이프라인을 사용하기 때문입니다.
+
+디코더 전용 모델로 추론을 실행하려면 `text-generation` 파이프라인을 사용하세요:
+
+```python
+>>> from transformers import pipeline
+>>> import torch
+
+>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
+
+>>> generator = pipeline('text-generation', model = 'openai-community/gpt2')
+>>> prompt = "Hello, I'm a language model"
+
+>>> generator(prompt, max_length = 30)
+[{'generated_text': "Hello, I'm a language model programmer so you can use some of my stuff. But you also need some sort of a C program to run."}]
+```
+
+인코더-디코더로 추론을 실행하려면 `text2text-generation` 파이프라인을 사용하세요:
+
+```python
+>>> text2text_generator = pipeline("text2text-generation", model = 'google/flan-t5-base')
+>>> prompt = "Translate from English to French: I'm very happy to see you"
+
+>>> text2text_generator(prompt)
+[{'generated_text': 'Je suis très heureuse de vous rencontrer.'}]
+```
+
+### 기본 모델 vs 지시/채팅 모델 [[base-vs-instructchat-models]]
+
+🤗 Hub에서 최근 사용 가능한 대부분의 대규모 언어 모델 체크포인트는 기본 버전과 지시(또는 채팅) 두 가지 버전이 제공됩니다. 예를 들어, [`tiiuae/falcon-7b`](https://huggingface.co/tiiuae/falcon-7b)와 [`tiiuae/falcon-7b-instruct`](https://huggingface.co/tiiuae/falcon-7b-instruct)가 있습니다.
+
+기본 모델은 초기 프롬프트가 주어졌을 때 텍스트를 완성하는 데 탁월하지만, 지시를 따라야 하거나 대화형 사용이 필요한 자연어 처리작업에는 이상적이지 않습니다. 이때 지시(채팅) 버전이 필요합니다. 이러한 체크포인트는 사전 훈련된 기본 버전을 지시사항과 대화 데이터로 추가 미세 조정한 결과입니다. 이 추가적인 미세 조정으로 인해 많은 자연어 처리 작업에 더 적합한 선택이 됩니다.
+
+[`tiiuae/falcon-7b-instruct`](https://huggingface.co/tiiuae/falcon-7b-instruct)를 사용하여 일반적인 자연어 처리 작업을 해결하는 데 사용할 수 있는 몇 가지 간단한 프롬프트를 살펴보겠습니다.
+
+### 자연어 처리 작업 [[nlp-tasks]]
+
+먼저, 환경을 설정해 보겠습니다:
+
+```bash
+pip install -q transformers accelerate
+```
+
+다음으로, 적절한 파이프라인("text-generation")을 사용하여 모델을 로드하겠습니다:
+
+```python
+>>> from transformers import pipeline, AutoTokenizer
+>>> import torch
+
+>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
+>>> model = "tiiuae/falcon-7b-instruct"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(model)
+>>> pipe = pipeline(
+... "text-generation",
+... model=model,
+... tokenizer=tokenizer,
+... torch_dtype=torch.bfloat16,
+... device_map="auto",
+... )
+```
+
+
+
+Falcon 모델은 bfloat16 데이터 타입을 사용하여 훈련되었으므로, 같은 타입을 사용하는 것을 권장합니다. 이를 위해서는 최신 버전의 CUDA가 필요하며, 최신 그래픽 카드에서 가장 잘 작동합니다.
+
+
+
+이제 파이프라인을 통해 모델을 로드했으니, 프롬프트를 사용하여 자연어 처리 작업을 해결하는 방법을 살펴보겠습니다.
+
+#### 텍스트 분류 [[text-classification]]
+
+텍스트 분류의 가장 일반적인 형태 중 하나는 감정 분석입니다. 이는 텍스트 시퀀스에 "긍정적", "부정적" 또는 "중립적"과 같은 레이블을 할당합니다. 주어진 텍스트(영화 리뷰)를 분류하도록 모델에 지시하는 프롬프트를 작성해 보겠습니다. 먼저 지시사항을 제공한 다음, 분류할 텍스트를 지정하겠습니다. 여기서 주목할 점은 단순히 거기서 끝내지 않고, 응답의 시작 부분인 `"Sentiment: "`을 추가한다는 것입니다:
+
+```python
+>>> torch.manual_seed(0)
+>>> prompt = """Classify the text into neutral, negative or positive.
+... Text: This movie is definitely one of my favorite movies of its kind. The interaction between respectable and morally strong characters is an ode to chivalry and the honor code amongst thieves and policemen.
+... Sentiment:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=10,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result: Classify the text into neutral, negative or positive.
+Text: This movie is definitely one of my favorite movies of its kind. The interaction between respectable and morally strong characters is an ode to chivalry and the honor code amongst thieves and policemen.
+Sentiment:
+Positive
+```
+
+결과적으로, 우리가 지시사항에서 제공한 목록에서 선택된 분류 레이블이 정확하게 포함되어 생성된 것을 확인할 수 있습니다!
+
+
+프롬프트 외에도 `max_new_tokens` 매개변수를 전달하는 것을 볼 수 있습니다. 이 매개변수는 모델이 생성할 토큰의 수를 제어하며, [텍스트 생성 전략](../generation_strategies) 가이드에서 배울 수 있는 여러 텍스트 생성 매개변수 중 하나입니다.
+
+
+
+#### 개체명 인식 [[named-entity-recognition]]
+
+개체명 인식(Named Entity Recognition, NER)은 텍스트에서 인물, 장소, 조직과 같은 명명된 개체를 찾는 작업입니다. 프롬프트의 지시사항을 수정하여 대규모 언어 모델이 이 작업을 수행하도록 해보겠습니다. 여기서는 `return_full_text = False`로 설정하여 출력에 프롬프트가 포함되지 않도록 하겠습니다:
+
+```python
+>>> torch.manual_seed(1) # doctest: +IGNORE_RESULT
+>>> prompt = """Return a list of named entities in the text.
+... Text: The Golden State Warriors are an American professional basketball team based in San Francisco.
+... Named entities:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=15,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"{seq['generated_text']}")
+- Golden State Warriors
+- San Francisco
+```
+
+보시다시피, 모델이 주어진 텍스트에서 두 개의 명명된 개체를 정확하게 식별했습니다.
+
+#### 번역 [[translation]]
+
+대규모 언어 모델이 수행할 수 있는 또 다른 작업은 번역입니다. 이 작업을 위해 인코더-디코더 모델을 사용할 수 있지만, 여기서는 예시의 단순성을 위해 꽤 좋은 성능을 보이는 Falcon-7b-instruct를 계속 사용하겠습니다. 다시 한 번, 모델에게 영어에서 이탈리아어로 텍스트를 번역하도록 지시하는 기본적인 프롬프트를 작성하는 방법은 다음과 같습니다:
+
+```python
+>>> torch.manual_seed(2) # doctest: +IGNORE_RESULT
+>>> prompt = """Translate the English text to Italian.
+... Text: Sometimes, I've believed as many as six impossible things before breakfast.
+... Translation:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=20,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"{seq['generated_text']}")
+A volte, ho creduto a sei impossibili cose prima di colazione.
+```
+
+여기서는 모델이 출력을 생성할 때 조금 더 유연해질 수 있도록 `do_sample=True`와 `top_k=10`을 추가했습니다.
+
+#### 텍스트 요약 [[text-summarization]]
+
+번역과 마찬가지로, 텍스트 요약은 출력이 입력에 크게 의존하는 또 다른 생성 작업이며, 인코더-디코더 기반 모델이 더 나은 선택일 수 있습니다. 그러나 디코더 기반의 모델도 이 작업에 사용될 수 있습니다. 이전에는 프롬프트의 맨 처음에 지시사항을 배치했습니다. 하지만 프롬프트의 맨 끝도 지시사항을 넣을 적절한 위치가 될 수 있습니다. 일반적으로 지시사항을 양 극단 중 하나에 배치하는 것이 더 좋습니다.
+
+```python
+>>> torch.manual_seed(3) # doctest: +IGNORE_RESULT
+>>> prompt = """Permaculture is a design process mimicking the diversity, functionality and resilience of natural ecosystems. The principles and practices are drawn from traditional ecological knowledge of indigenous cultures combined with modern scientific understanding and technological innovations. Permaculture design provides a framework helping individuals and communities develop innovative, creative and effective strategies for meeting basic needs while preparing for and mitigating the projected impacts of climate change.
+... Write a summary of the above text.
+... Summary:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=30,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"{seq['generated_text']}")
+Permaculture is an ecological design mimicking natural ecosystems to meet basic needs and prepare for climate change. It is based on traditional knowledge and scientific understanding.
+```
+
+#### 질의 응답 [[question-answering]]
+
+질의 응답 작업을 위해 프롬프트를 다음과 같은 논리적 구성요소로 구조화할 수 있습니다. 지시사항, 맥락, 질문, 그리고 모델이 답변 생성을 시작하도록 유도하는 선도 단어나 구문(`"Answer:"`) 을 사용할 수 있습니다:
+
+```python
+>>> torch.manual_seed(4) # doctest: +IGNORE_RESULT
+>>> prompt = """Answer the question using the context below.
+... Context: Gazpacho is a cold soup and drink made of raw, blended vegetables. Most gazpacho includes stale bread, tomato, cucumbers, onion, bell peppers, garlic, olive oil, wine vinegar, water, and salt. Northern recipes often include cumin and/or pimentón (smoked sweet paprika). Traditionally, gazpacho was made by pounding the vegetables in a mortar with a pestle; this more laborious method is still sometimes used as it helps keep the gazpacho cool and avoids the foam and silky consistency of smoothie versions made in blenders or food processors.
+... Question: What modern tool is used to make gazpacho?
+... Answer:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=10,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result: Modern tools often used to make gazpacho include
+```
+
+#### 추론 [[reasoning]]
+
+추론은 대규모 언어 모델(LLM)에게 가장 어려운 작업 중 하나이며, 좋은 결과를 얻기 위해서는 종종 [생각의 사슬(Chain-of-thought, CoT)](#chain-of-thought)과 같은 고급 프롬프팅 기법을 적용해야 합니다. 간단한 산술 작업에 대해 기본적인 프롬프트로 모델이 추론할 수 있는지 시도해 보겠습니다:
+
+```python
+>>> torch.manual_seed(5) # doctest: +IGNORE_RESULT
+>>> prompt = """There are 5 groups of students in the class. Each group has 4 students. How many students are there in the class?"""
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=30,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result:
+There are a total of 5 groups, so there are 5 x 4=20 students in the class.
+```
+
+정확한 답변이 생성되었습니다! 복잡성을 조금 높여보고 기본적인 프롬프트로도 여전히 해결할 수 있는지 확인해 보겠습니다:
+
+```python
+>>> torch.manual_seed(6)
+>>> prompt = """I baked 15 muffins. I ate 2 muffins and gave 5 muffins to a neighbor. My partner then bought 6 more muffins and ate 2. How many muffins do we now have?"""
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=10,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result:
+The total number of muffins now is 21
+```
+
+정답은 12여야 하는데 21이라는 잘못된 답변이 나왔습니다. 이 경우, 프롬프트가 너무 기본적이거나 모델의 크기가 작아서 생긴 문제일 수 있습니다. 우리는 Falcon의 가장 작은 버전을 선택했습니다. 추론은 큰 모델에게도 어려운 작업이지만, 더 큰 모델들이 더 나은 성능을 보일 가능성이 높습니다.
+
+## 대규모 언어 모델 프롬프트 작성의 모범 사례 [[best-practices-of-llm-prompting]]
+
+이 섹션에서는 프롬프트 결과를 향상시킬 수 있는 모범 사례 목록을 작성했습니다:
+
+* 작업할 모델을 선택할 때 최신 및 가장 강력한 모델이 더 나은 성능을 발휘할 가능성이 높습니다.
+* 간단하고 짧은 프롬프트로 시작하여 점진적으로 개선해 나가세요.
+* 프롬프트의 시작 부분이나 맨 끝에 지시사항을 배치하세요. 대규모 컨텍스트를 다룰 때, 모델들은 어텐션 복잡도가 2차적으로 증가하는 것을 방지하기 위해 다양한 최적화를 적용합니다. 이렇게 함으로써 모델이 프롬프트의 중간보다 시작이나 끝 부분에 더 주의를 기울일 수 있습니다.
+* 지시사항을 적용할 텍스트와 명확하게 분리해보세요. (이에 대해서는 다음 섹션에서 더 자세히 다룹니다.)
+* 작업과 원하는 결과에 대해 구체적이고 풍부한 설명을 제공하세요. 형식, 길이, 스타일, 언어 등을 명확하게 작성해야 합니다.
+* 모호한 설명과 지시사항을 피하세요.
+* "하지 말라"는 지시보다는 "무엇을 해야 하는지"를 말하는 지시를 사용하는 것이 좋습니다.
+* 첫 번째 단어를 쓰거나 첫 번째 문장을 시작하여 출력을 올바른 방향으로 "유도"하세요.
+* [퓨샷(Few-shot) 프롬프팅](#few-shot-prompting) 및 [생각의 사슬(Chain-of-thought, CoT)](#chain-of-thought) 같은 고급 기술을 사용해보세요.
+* 프롬프트의 견고성을 평가하기 위해 다른 모델로도 테스트하세요.
+* 프롬프트의 버전을 관리하고 성능을 추적하세요.
+
+## 고급 프롬프트 기법 [[advanced-prompting-techniques]]
+
+### 퓨샷(Few-shot) 프롬프팅 [[few-shot-prompting]]
+
+위 섹션의 기본 프롬프트들은 "제로샷(Zero-shot)" 프롬프트의 예시입니다. 이는 모델에 지시사항과 맥락은 주어졌지만, 해결책이 포함된 예시는 제공되지 않았다는 의미입니다. 지시 데이터셋으로 미세 조정된 대규모 언어 모델은 일반적으로 이러한 "제로샷" 작업에서 좋은 성능을 보입니다. 하지만 여러분의 작업이 더 복잡하거나 미묘한 차이가 있을 수 있고, 아마도 지시사항만으로는 모델이 포착하지 못하는 출력에 대한 요구사항이 있을 수 있습니다. 이런 경우에는 퓨샷(Few-shot) 프롬프팅이라는 기법을 시도해 볼 수 있습니다.
+
+퓨샷 프롬프팅에서는 프롬프트에 예시를 제공하여 모델에 더 많은 맥락을 주고 성능을 향상시킵니다. 이 예시들은 모델이 예시의 패턴을 따라 출력을 생성하도록 조건화합니다.
+
+다음은 예시입니다:
+
+```python
+>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
+>>> prompt = """Text: The first human went into space and orbited the Earth on April 12, 1961.
+... Date: 04/12/1961
+... Text: The first-ever televised presidential debate in the United States took place on September 28, 1960, between presidential candidates John F. Kennedy and Richard Nixon.
+... Date:"""
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=8,
+... do_sample=True,
+... top_k=10,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result: Text: The first human went into space and orbited the Earth on April 12, 1961.
+Date: 04/12/1961
+Text: The first-ever televised presidential debate in the United States took place on September 28, 1960, between presidential candidates John F. Kennedy and Richard Nixon.
+Date: 09/28/1960
+```
+
+위의 코드 스니펫에서는 모델에 원하는 출력을 보여주기 위해 단일 예시를 사용했으므로, 이를 "원샷(One-shot)" 프롬프팅이라고 부를 수 있습니다. 그러나 작업의 복잡성에 따라 하나 이상의 예시를 사용해야 할 수도 있습니다.
+
+퓨샷 프롬프팅 기법의 한계:
+- 대규모 언어 모델이 예시의 패턴을 파악할 수 있지만, 이 기법은 복잡한 추론 작업에는 잘 작동하지 않습니다.
+- 퓨샷 프롬프팅을 적용하면 프롬프트의 길이가 길어집니다. 토큰 수가 많은 프롬프트는 계산량과 지연 시간을 증가시킬 수 있으며 프롬프트 길이에도 제한이 있습니다.
+- 때로는 여러 예시가 주어질 때, 모델은 의도하지 않은 패턴을 학습할 수 있습니다. 예를 들어, 세 번째 영화 리뷰가 항상 부정적이라고 학습할 수 있습니다.
+
+### 생각의 사슬(Chain-of-thought, CoT) [[chain-of-thought]]
+
+생각의 사슬(Chain-of-thought, CoT) 프롬프팅은 모델이 중간 추론 단계를 생성하도록 유도하는 기법으로, 복잡한 추론 작업의 결과를 개선합니다.
+
+모델이 추론 단계를 생성하도록 유도하는 두 가지 방법이 있습니다:
+- 질문에 대한 상세한 답변을 예시로 제시하는 퓨샷 프롬프팅을 통해 모델에게 문제를 어떻게 해결해 나가는지 보여줍니다.
+- "단계별로 생각해 봅시다" 또는 "깊게 숨을 쉬고 문제를 단계별로 해결해 봅시다"와 같은 문구를 추가하여 모델에게 추론하도록 지시합니다.
+
+[reasoning section](#reasoning)의 머핀 예시에 생각의 사슬(Chain-of-thought, CoT) 기법을 적용하고 [HuggingChat](https://huggingface.co/chat/)에서 사용할 수 있는 (`tiiuae/falcon-180B-chat`)과 같은 더 큰 모델을 사용하면, 추론 결과가 크게 개선됩니다:
+
+```text
+단계별로 살펴봅시다:
+1. 처음에 15개의 머핀이 있습니다.
+2. 2개의 머핀을 먹으면 13개의 머핀이 남습니다.
+3. 이웃에게 5개의 머핀을 주면 8개의 머핀이 남습니다.
+4. 파트너가 6개의 머핀을 더 사오면 총 머핀 수는 14개가 됩니다.
+5. 파트너가 2개의 머핀을 먹으면 12개의 머핀이 남습니다.
+따라서, 현재 12개의 머핀이 있습니다.
+```
+
+## 프롬프팅 vs 미세 조정 [[prompting-vs-fine-tuning]]
+
+프롬프트를 최적화하여 훌륭한 결과를 얻을 수 있지만, 여전히 모델을 미세 조정하는 것이 더 좋을지 고민할 수 있습니다. 다음은 더 작은 모델을 미세 조정하는 것이 선호되는 시나리오입니다:
+
+- 도메인이 대규모 언어 모델이 사전 훈련된 것과 크게 다르고 광범위한 프롬프트 최적화로도 충분한 결과를 얻지 못한 경우.
+- 저자원 언어에서 모델이 잘 작동해야 하는 경우.
+- 엄격한 규제 하에 있는 민감한 데이터로 모델을 훈련해야 하는 경우.
+- 비용, 개인정보 보호, 인프라 또는 기타 제한으로 인해 작은 모델을 사용해야 하는 경우.
+
+위의 모든 예시에서, 모델을 미세 조정하기 위해 충분히 큰 도메인별 데이터셋을 이미 가지고 있거나 합리적인 비용으로 쉽게 얻을 수 있는지 확인해야 합니다. 또한 모델을 미세 조정할 충분한 시간과 자원이 필요합니다.
+
+만약 위의 예시들이 여러분의 경우에 해당하지 않는다면, 프롬프트를 최적화하는 것이 더 유익할 수 있습니다.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/question_answering.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/question_answering.md
new file mode 100644
index 0000000000000000000000000000000000000000..8309dd7d753244f355747d0bff29e564df2cde33
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/question_answering.md
@@ -0,0 +1,422 @@
+
+
+# 질의 응답(Question Answering)[[question-answering]]
+
+[[open-in-colab]]
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/question-answering)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에, 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+여러분의 모델을 업로드하고 커뮤니티에 공유할 수 있도록 Hugging Face 계정에 로그인하는 것이 좋습니다. 메시지가 표시되면 토큰을 입력해서 로그인합니다:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## SQuAD 데이터 세트 가져오기[[load-squad-dataset]]
+
+먼저 🤗 Datasets 라이브러리에서 SQuAD 데이터 세트의 일부를 가져옵니다. 이렇게 하면 전체 데이터 세트로 훈련하며 더 많은 시간을 할애하기 전에 모든 것이 잘 작동하는지 실험하고 확인할 수 있습니다.
+
+```py
+>>> from datasets import load_dataset
+
+>>> squad = load_dataset("squad", split="train[:5000]")
+```
+
+데이터 세트의 분할된 `train`을 [`~datasets.Dataset.train_test_split`] 메소드를 사용해 훈련 데이터 세트와 테스트 데이터 세트로 나누어줍니다:
+
+```py
+>>> squad = squad.train_test_split(test_size=0.2)
+```
+
+그리고나서 예시로 데이터를 하나 살펴봅니다:
+
+```py
+>>> squad["train"][0]
+{'answers': {'answer_start': [515], 'text': ['Saint Bernadette Soubirous']},
+ 'context': 'Architecturally, the school has a Catholic character. Atop the Main Building\'s gold dome is a golden statue of the Virgin Mary. Immediately in front of the Main Building and facing it, is a copper statue of Christ with arms upraised with the legend "Venite Ad Me Omnes". Next to the Main Building is the Basilica of the Sacred Heart. Immediately behind the basilica is the Grotto, a Marian place of prayer and reflection. It is a replica of the grotto at Lourdes, France where the Virgin Mary reputedly appeared to Saint Bernadette Soubirous in 1858. At the end of the main drive (and in a direct line that connects through 3 statues and the Gold Dome), is a simple, modern stone statue of Mary.',
+ 'id': '5733be284776f41900661182',
+ 'question': 'To whom did the Virgin Mary allegedly appear in 1858 in Lourdes France?',
+ 'title': 'University_of_Notre_Dame'
+}
+```
+
+이 중에서 몇 가지 중요한 항목이 있습니다:
+
+- `answers`: 답안 토큰의 시작 위치와 답안 텍스트
+- `context`: 모델이 답을 추출하는데 필요한 배경 지식
+- `question`: 모델이 답해야 하는 질문
+
+## 전처리[[preprocess]]
+
+
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator()
+```
+
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+```
+
+
+
+## 훈련[[train]]
+
+
+
+
+
+[`Trainer`]를 이용해 모델을 미세 조정하는 것에 익숙하지 않다면, [여기](../training#train-with-pytorch-trainer)에서 기초 튜토리얼을 살펴보세요!
+
+
+
+이제 모델 훈련을 시작할 준비가 되었습니다! [`AutoModelForQuestionAnswering`]으로 DistilBERT를 가져옵니다:
+
+```py
+>>> from transformers import AutoModelForQuestionAnswering, TrainingArguments, Trainer
+
+>>> model = AutoModelForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+이제 세 단계만 남았습니다:
+
+1. [`TrainingArguments`]에서 훈련 하이퍼파라미터를 정합니다. 꼭 필요한 매개변수는 모델을 저장할 위치를 지정하는 `output_dir` 입니다. `push_to_hub=True`로 설정해서 이 모델을 Hub로 푸시합니다 (모델을 업로드하려면 Hugging Face에 로그인해야 합니다).
+2. 모델, 데이터 세트, 토크나이저, 데이터 콜레이터와 함께 [`Trainer`]에 훈련 인수들을 전달합니다.
+3. [`~Trainer.train`]을 호출해서 모델을 미세 조정합니다.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_qa_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_squad["train"],
+... eval_dataset=tokenized_squad["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면, [`~transformers.Trainer.push_to_hub`] 매소드를 사용해 모델을 Hub에 공유해서 모든 사람들이 사용할 수 있게 공유해주세요:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras로 모델을 미세 조정하는 것에 익숙하지 않다면, [여기](../training#train-a-tensorflow-model-with-keras)에서 기초 튜토리얼을 살펴보세요!
+
+
+TensorFlow를 이용한 모델을 미세 조정하려면 옵티마이저 함수, 학습률 스케쥴 및 몇 가지 훈련 하이퍼파라미터를 설정하는 것부터 시작해야합니다:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_epochs = 2
+>>> total_train_steps = (len(tokenized_squad["train"]) // batch_size) * num_epochs
+>>> optimizer, schedule = create_optimizer(
+... init_lr=2e-5,
+... num_warmup_steps=0,
+... num_train_steps=total_train_steps,
+... )
+```
+
+그 다음 [`TFAutoModelForQuestionAnswering`]으로 DistilBERT를 가져옵니다:
+
+```py
+>>> from transformers import TFAutoModelForQuestionAnswering
+
+>>> model = TFAutoModelForQuestionAnswering("distilbert/distilbert-base-uncased")
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`]을 사용해서 데이터 세트를 `tf.data.Dataset` 형식으로 변환합니다:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_squad["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_squad["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method)로 훈련할 모델을 설정합니다:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+마지막으로 모델을 Hub로 푸시할 방법을 설정합니다. [`~transformers.PushToHubCallback`]에서 모델과 토크나이저를 푸시할 경로를 설정합니다:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> callback = PushToHubCallback(
+... output_dir="my_awesome_qa_model",
+... tokenizer=tokenizer,
+... )
+```
+
+드디어 모델 훈련을 시작할 준비가 되었습니다! 훈련 데이터 세트와 평가 데이터 세트, 에폭 수, 콜백을 설정한 후 [`fit`](https://keras.io/api/models/model_training_apis/#fit-method)을 이용해 모델을 미세 조정합니다:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3, callbacks=[callback])
+```
+훈련이 완료되면 모델이 자동으로 Hub에 업로드되어 누구나 사용할 수 있습니다!
+
+
+
+
+
+질의 응답을 위해 모델을 미세 조정하는 방법에 대한 더 자세한 예시는 [PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb) 또는 [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering-tf.ipynb)을 참조하세요.
+
+
+
+## 평가[[evaluate]]
+
+질의 응답을 평가하려면 상당한 양의 후처리가 필요합니다. 시간이 너무 많이 걸리지 않도록 이 가이드에서는 평가 단계를 생략합니다. [`Trainer`]는 훈련 과정에서 평가 손실(evaluation loss)을 계속 계산하기 때문에 모델의 성능을 대략적으로 알 수 있습니다.
+
+시간에 여유가 있고 질의 응답 모델을 평가하는 방법에 관심이 있다면 🤗 Hugging Face Course의 [Question answering](https://huggingface.co/course/chapter7/7?fw=pt#postprocessing) 챕터를 살펴보세요!
+
+## 추론[[inference]]
+
+이제 모델을 미세 조정했으니 추론에 사용할 수 있습니다!
+
+질문과 모델이 예측하기 원하는 문맥(context)를 생각해보세요:
+
+```py
+>>> question = "How many programming languages does BLOOM support?"
+>>> context = "BLOOM has 176 billion parameters and can generate text in 46 languages natural languages and 13 programming languages."
+```
+
+추론을 위해 미세 조정한 모델을 테스트하는 가장 쉬운 방법은 [`pipeline`]을 사용하는 것 입니다. 모델을 사용해 질의 응답을 하기 위해서 `pipeline`을 인스턴스화하고 텍스트를 입력합니다:
+
+```py
+>>> from transformers import pipeline
+
+>>> question_answerer = pipeline("question-answering", model="my_awesome_qa_model")
+>>> question_answerer(question=question, context=context)
+{'score': 0.2058267742395401,
+ 'start': 10,
+ 'end': 95,
+ 'answer': '176 billion parameters and can generate text in 46 languages natural languages and 13'}
+```
+
+원한다면 `pipeline`의 결과를 직접 복제할 수도 있습니다:
+
+
+
+텍스트를 토큰화해서 PyTorch 텐서를 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_qa_model")
+>>> inputs = tokenizer(question, context, return_tensors="pt")
+```
+
+모델에 입력을 전달하고 `logits`을 반환합니다:
+
+```py
+>>> from transformers import AutoModelForQuestionAnswering
+
+>>> model = AutoModelForQuestionAnswering.from_pretrained("my_awesome_qa_model")
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+```
+
+모델의 출력에서 시작 및 종료 위치가 어딘지 가장 높은 확률을 얻습니다:
+
+```py
+>>> answer_start_index = outputs.start_logits.argmax()
+>>> answer_end_index = outputs.end_logits.argmax()
+```
+
+예측된 토큰을 해독해서 답을 얻습니다:
+
+```py
+>>> predict_answer_tokens = inputs.input_ids[0, answer_start_index : answer_end_index + 1]
+>>> tokenizer.decode(predict_answer_tokens)
+'176 billion parameters and can generate text in 46 languages natural languages and 13'
+```
+
+
+텍스트를 토큰화해서 TensorFlow 텐서를 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_qa_model")
+>>> inputs = tokenizer(question, text, return_tensors="tf")
+```
+
+모델에 입력을 전달하고 `logits`을 반환합니다:
+
+```py
+>>> from transformers import TFAutoModelForQuestionAnswering
+
+>>> model = TFAutoModelForQuestionAnswering.from_pretrained("my_awesome_qa_model")
+>>> outputs = model(**inputs)
+```
+
+모델의 출력에서 시작 및 종료 위치가 어딘지 가장 높은 확률을 얻습니다:
+
+```py
+>>> answer_start_index = int(tf.math.argmax(outputs.start_logits, axis=-1)[0])
+>>> answer_end_index = int(tf.math.argmax(outputs.end_logits, axis=-1)[0])
+```
+
+예측된 토큰을 해독해서 답을 얻습니다:
+
+```py
+>>> predict_answer_tokens = inputs.input_ids[0, answer_start_index : answer_end_index + 1]
+>>> tokenizer.decode(predict_answer_tokens)
+'176 billion parameters and can generate text in 46 languages natural languages and 13'
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/semantic_segmentation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/semantic_segmentation.md
new file mode 100644
index 0000000000000000000000000000000000000000..04a727448dacd392fc9d1ac449e53f52fe6a69a1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/semantic_segmentation.md
@@ -0,0 +1,587 @@
+
+
+# 의미적 분할(Semantic segmentation)[[semantic-segmentation]]
+
+[[open-in-colab]]
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/image-segmentation)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 모든 라이브러리가 설치되었는지 확인하세요:
+
+```bash
+pip install -q datasets transformers evaluate
+```
+커뮤니티에 모델을 업로드하고 공유할 수 있도록 Hugging Face 계정에 로그인하는 것을 권장합니다. 프롬프트가 나타나면 토큰을 입력하여 로그인하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## SceneParse150 데이터 세트 불러오기[[load-sceneparse150-dataset]]
+
+🤗 Datasets 라이브러리에서 SceneParse150 데이터 세트의 더 작은 부분 집합을 가져오는 것으로 시작합니다. 이렇게 하면 데이터 세트 전체에 대한 훈련에 많은 시간을 할애하기 전에 실험을 통해 모든 것이 제대로 작동하는지 확인할 수 있습니다.
+
+```py
+>>> from datasets import load_dataset
+
+>>> ds = load_dataset("scene_parse_150", split="train[:50]")
+```
+
+데이터 세트의 `train`을 [`~datasets.Dataset.train_test_split`] 메소드를 사용하여 훈련 및 테스트 세트로 분할하세요:
+
+```py
+>>> ds = ds.train_test_split(test_size=0.2)
+>>> train_ds = ds["train"]
+>>> test_ds = ds["test"]
+```
+
+그리고 예시를 살펴보세요:
+
+```py
+>>> train_ds[0]
+{'image': ,
+ 'annotation': ,
+ 'scene_category': 368}
+```
+
+- `image`: 장면의 PIL 이미지입니다.
+- `annotation`: 분할 지도(segmentation map)의 PIL 이미지입니다. 모델의 타겟이기도 합니다.
+- `scene_category`: "주방" 또는 "사무실"과 같이 이미지 장면을 설명하는 카테고리 ID입니다. 이 가이드에서는 둘 다 PIL 이미지인 `image`와 `annotation`만을 사용합니다.
+
+나중에 모델을 설정할 때 유용하게 사용할 수 있도록 레이블 ID를 레이블 클래스에 매핑하는 사전도 만들고 싶을 것입니다. Hub에서 매핑을 다운로드하고 `id2label` 및 `label2id` 사전을 만드세요:
+
+```py
+>>> import json
+>>> from pathlib import Path
+>>> from huggingface_hub import hf_hub_download
+
+>>> repo_id = "huggingface/label-files"
+>>> filename = "ade20k-id2label.json"
+>>> id2label = json.loads(Path(hf_hub_download(repo_id, filename, repo_type="dataset")).read_text())
+>>> id2label = {int(k): v for k, v in id2label.items()}
+>>> label2id = {v: k for k, v in id2label.items()}
+>>> num_labels = len(id2label)
+```
+
+## 전처리하기[[preprocess]
+
+다음 단계는 모델에 사용할 이미지와 주석을 준비하기 위해 SegFormer 이미지 프로세서를 불러오는 것입니다. 우리가 사용하는 데이터 세트와 같은 일부 데이터 세트는 배경 클래스로 제로 인덱스를 사용합니다. 하지만 배경 클래스는 150개의 클래스에 실제로는 포함되지 않기 때문에 `do_reduce_labels=True` 를 설정해 모든 레이블에서 배경 클래스를 제거해야 합니다. 제로 인덱스는 `255`로 대체되므로 SegFormer의 손실 함수에서 무시됩니다:
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> checkpoint = "nvidia/mit-b0"
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint, do_reduce_labels=True)
+```
+
+
+
+
+이미지 데이터 세트에 데이터 증강을 적용하여 과적합에 대해 모델을 보다 강건하게 만드는 것이 일반적입니다. 이 가이드에서는 [torchvision](https://pytorch.org/vision/stable/index.html)의 [`ColorJitter`](https://pytorch.org/vision/stable/generated/torchvision.transforms.ColorJitter.html)를 사용하여 이미지의 색상 속성을 임의로 변경합니다. 하지만, 자신이 원하는 이미지 라이브러리를 사용할 수도 있습니다.
+
+```py
+>>> from torchvision.transforms import ColorJitter
+
+>>> jitter = ColorJitter(brightness=0.25, contrast=0.25, saturation=0.25, hue=0.1)
+```
+
+이제 모델에 사용할 이미지와 주석을 준비하기 위해 두 개의 전처리 함수를 만듭니다. 이 함수들은 이미지를 `pixel_values`로, 주석을 `labels`로 변환합니다. 훈련 세트의 경우 이미지 프로세서에 이미지를 제공하기 전에 `jitter`를 적용합니다. 테스트 세트의 경우 이미지 프로세서는 `images`를 자르고 정규화하며, 테스트 중에는 데이터 증강이 적용되지 않으므로 `labels`만 자릅니다.
+
+```py
+>>> def train_transforms(example_batch):
+... images = [jitter(x) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+
+
+>>> def val_transforms(example_batch):
+... images = [x for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+```
+
+모든 데이터 세트에 `jitter`를 적용하려면, 🤗 Datasets [`~datasets.Dataset.set_transform`] 함수를 사용하세요. 즉시 변환이 적용되기 때문에 더 빠르고 디스크 공간을 덜 차지합니다:
+
+```py
+>>> train_ds.set_transform(train_transforms)
+>>> test_ds.set_transform(val_transforms)
+```
+
+
+
+
+
+
+
+이미지 데이터 세트에 데이터 증강을 적용하여 과적합에 대해 모델을 보다 강건하게 만드는 것이 일반적입니다. 이 가이드에서는 [`tf.image`](https://www.tensorflow.org/api_docs/python/tf/image)를 사용하여 이미지의 색상 속성을 임의로 변경합니다. 하지만, 자신이 원하는 이미지 라이브러리를 사용할 수도 있습니다.
+
+별개의 두 변환 함수를 정의합니다:
+- 이미지 증강을 포함하는 학습 데이터 변환
+- 🤗 Transformers의 컴퓨터 비전 모델은 채널 우선 레이아웃을 기대하기 때문에, 이미지만 바꾸는 검증 데이터 변환
+
+```py
+>>> import tensorflow as tf
+
+
+>>> def aug_transforms(image):
+... image = tf.keras.utils.img_to_array(image)
+... image = tf.image.random_brightness(image, 0.25)
+... image = tf.image.random_contrast(image, 0.5, 2.0)
+... image = tf.image.random_saturation(image, 0.75, 1.25)
+... image = tf.image.random_hue(image, 0.1)
+... image = tf.transpose(image, (2, 0, 1))
+... return image
+
+
+>>> def transforms(image):
+... image = tf.keras.utils.img_to_array(image)
+... image = tf.transpose(image, (2, 0, 1))
+... return image
+```
+
+그런 다음 모델을 위해 두 개의 전처리 함수를 만들어 이미지 및 주석 배치를 준비합니다. 이 함수들은 이미지 변환을 적용하고 이전에 로드한 `image_processor`를 사용하여 이미지를 `pixel_values`로, 주석을 `label`로 변환합니다. `ImageProcessor` 는 이미지의 크기 조정과 정규화도 처리합니다.
+
+```py
+>>> def train_transforms(example_batch):
+... images = [aug_transforms(x.convert("RGB")) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+
+
+>>> def val_transforms(example_batch):
+... images = [transforms(x.convert("RGB")) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+```
+
+전체 데이터 집합에 전처리 변환을 적용하려면 🤗 Datasets [`~datasets.Dataset.set_transform`] 함수를 사용하세요.
+즉시 변환이 적용되기 때문에 더 빠르고 디스크 공간을 덜 차지합니다:
+
+```py
+>>> train_ds.set_transform(train_transforms)
+>>> test_ds.set_transform(val_transforms)
+```
+
+
+
+## 평가하기[[evaluate]]
+
+훈련 중에 메트릭을 포함하면 모델의 성능을 평가하는 데 도움이 되는 경우가 많습니다. 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리를 사용하여 평가 방법을 빠르게 로드할 수 있습니다. 이 태스크에서는 [mean Intersection over Union](https://huggingface.co/spaces/evaluate-metric/accuracy) (IoU) 메트릭을 로드하세요 (메트릭을 로드하고 계산하는 방법에 대해 자세히 알아보려면 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour)를 살펴보세요).
+
+```py
+>>> import evaluate
+
+>>> metric = evaluate.load("mean_iou")
+```
+
+그런 다음 메트릭을 [`~evaluate.EvaluationModule.compute`]하는 함수를 만듭니다. 예측을 먼저 로짓으로 변환한 다음, 레이블의 크기에 맞게 모양을 다시 지정해야 [`~evaluate.EvaluationModule.compute`]를 호출할 수 있습니다:
+
+
+
+
+```py
+>>> import numpy as np
+>>> import torch
+>>> from torch import nn
+
+>>> def compute_metrics(eval_pred):
+... with torch.no_grad():
+... logits, labels = eval_pred
+... logits_tensor = torch.from_numpy(logits)
+... logits_tensor = nn.functional.interpolate(
+... logits_tensor,
+... size=labels.shape[-2:],
+... mode="bilinear",
+... align_corners=False,
+... ).argmax(dim=1)
+
+... pred_labels = logits_tensor.detach().cpu().numpy()
+... metrics = metric.compute(
+... predictions=pred_labels,
+... references=labels,
+... num_labels=num_labels,
+... ignore_index=255,
+... reduce_labels=False,
+... )
+... for key, value in metrics.items():
+... if isinstance(value, np.ndarray):
+... metrics[key] = value.tolist()
+... return metrics
+```
+
+
+
+
+
+
+
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... logits = tf.transpose(logits, perm=[0, 2, 3, 1])
+... logits_resized = tf.image.resize(
+... logits,
+... size=tf.shape(labels)[1:],
+... method="bilinear",
+... )
+
+... pred_labels = tf.argmax(logits_resized, axis=-1)
+... metrics = metric.compute(
+... predictions=pred_labels,
+... references=labels,
+... num_labels=num_labels,
+... ignore_index=-1,
+... reduce_labels=image_processor.do_reduce_labels,
+... )
+
+... per_category_accuracy = metrics.pop("per_category_accuracy").tolist()
+... per_category_iou = metrics.pop("per_category_iou").tolist()
+
+... metrics.update({f"accuracy_{id2label[i]}": v for i, v in enumerate(per_category_accuracy)})
+... metrics.update({f"iou_{id2label[i]}": v for i, v in enumerate(per_category_iou)})
+... return {"val_" + k: v for k, v in metrics.items()}
+```
+
+
+
+
+이제 `compute_metrics` 함수를 사용할 준비가 되었습니다. 트레이닝을 설정할 때 이 함수로 돌아가게 됩니다.
+
+## 학습하기[[train]]
+
+
+
+
+만약 [`Trainer`]를 사용해 모델을 미세 조정하는 것에 익숙하지 않다면, [여기](../training#finetune-with-trainer)에서 기본 튜토리얼을 살펴보세요!
+
+
+
+이제 모델 학습을 시작할 준비가 되었습니다! [`AutoModelForSemanticSegmentation`]로 SegFormer를 불러오고, 모델에 레이블 ID와 레이블 클래스 간의 매핑을 전달합니다:
+
+```py
+>>> from transformers import AutoModelForSemanticSegmentation, TrainingArguments, Trainer
+
+>>> model = AutoModelForSemanticSegmentation.from_pretrained(checkpoint, id2label=id2label, label2id=label2id)
+```
+
+이제 세 단계만 남았습니다:
+
+1. 학습 하이퍼파라미터를 [`TrainingArguments`]에 정의합니다. `image` 열이 삭제되기 때문에 사용하지 않는 열을 제거하지 않는 것이 중요합니다. `image` 열이 없으면 `pixel_values`을 생성할 수 없습니다. 이런 경우를 방지하려면 `remove_unused_columns=False`로 설정하세요! 유일하게 필요한 다른 매개변수는 모델을 저장할 위치를 지정하는 `output_dir`입니다. `push_to_hub=True`를 설정하여 이 모델을 Hub에 푸시합니다(모델을 업로드하려면 Hugging Face에 로그인해야 합니다). 각 에포크가 끝날 때마다 [`Trainer`]가 IoU 메트릭을 평가하고 학습 체크포인트를 저장합니다.
+2. 모델, 데이터 세트, 토크나이저, 데이터 콜레이터, `compute_metrics` 함수와 함께 학습 인자를 [`Trainer`]에 전달하세요.
+3. 모델을 미세 조정하기 위해 [`~Trainer.train`]를 호출하세요.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="segformer-b0-scene-parse-150",
+... learning_rate=6e-5,
+... num_train_epochs=50,
+... per_device_train_batch_size=2,
+... per_device_eval_batch_size=2,
+... save_total_limit=3,
+... eval_strategy="steps",
+... save_strategy="steps",
+... save_steps=20,
+... eval_steps=20,
+... logging_steps=1,
+... eval_accumulation_steps=5,
+... remove_unused_columns=False,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=train_ds,
+... eval_dataset=test_ds,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+학습이 완료되면, 누구나 모델을 사용할 수 있도록 [`~transformers.Trainer.push_to_hub`] 메서드를 사용해 Hub에 모델을 공유하세요:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+
+
+Keras로 모델을 미세 조정하는 데 익숙하지 않은 경우, 먼저 [기본 튜토리얼](../training#train-a-tensorflow-model-with-keras)을 확인해보세요!
+
+
+
+TensorFlow에서 모델을 미세 조정하려면 다음 단계를 따르세요:
+1. 학습 하이퍼파라미터를 정의하고 옵티마이저와 학습률 스케쥴러를 설정하세요.
+2. 사전 학습된 모델을 인스턴스화하세요.
+3. 🤗 Dataset을 `tf.data.Dataset`로 변환하세요.
+4. 모델을 컴파일하세요.
+5. 콜백을 추가하여 메트릭을 계산하고 🤗 Hub에 모델을 업로드하세요.
+6. `fit()` 메서드를 사용하여 훈련을 실행하세요.
+
+하이퍼파라미터, 옵티마이저, 학습률 스케쥴러를 정의하는 것으로 시작하세요:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 2
+>>> num_epochs = 50
+>>> num_train_steps = len(train_ds) * num_epochs
+>>> learning_rate = 6e-5
+>>> weight_decay_rate = 0.01
+
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=learning_rate,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=weight_decay_rate,
+... num_warmup_steps=0,
+... )
+```
+
+그런 다음 레이블 매핑과 함께 [`TFAutoModelForSemanticSegmentation`]을 사용하여 SegFormer를 불러오고 옵티마이저로 컴파일합니다. 트랜스포머 모델은 모두 디폴트로 태스크 관련 손실 함수가 있으므로 원치 않으면 지정할 필요가 없습니다:
+
+```py
+>>> from transformers import TFAutoModelForSemanticSegmentation
+
+>>> model = TFAutoModelForSemanticSegmentation.from_pretrained(
+... checkpoint,
+... id2label=id2label,
+... label2id=label2id,
+... )
+>>> model.compile(optimizer=optimizer) # 손실 함수 인자가 없습니다!
+```
+
+[`~datasets.Dataset.to_tf_dataset`] 와 [`DefaultDataCollator`]를 사용해 데이터 세트를 `tf.data.Dataset` 포맷으로 변환하세요:
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+
+>>> tf_train_dataset = train_ds.to_tf_dataset(
+... columns=["pixel_values", "label"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+
+>>> tf_eval_dataset = test_ds.to_tf_dataset(
+... columns=["pixel_values", "label"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+```
+
+예측으로 정확도를 계산하고 모델을 🤗 Hub로 푸시하려면 [Keras callbacks](../main_classes/keras_callbacks)를 사용하세요. `compute_metrics` 함수를 [`KerasMetricCallback`]에 전달하고, 모델 업로드를 위해 [`PushToHubCallback`]를 사용하세요:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback, PushToHubCallback
+
+>>> metric_callback = KerasMetricCallback(
+... metric_fn=compute_metrics, eval_dataset=tf_eval_dataset, batch_size=batch_size, label_cols=["labels"]
+... )
+
+>>> push_to_hub_callback = PushToHubCallback(output_dir="scene_segmentation", tokenizer=image_processor)
+
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+이제 모델을 훈련할 준비가 되었습니다! 훈련 및 검증 데이터 세트, 에포크 수와 함께 `fit()`을 호출하고, 콜백을 사용하여 모델을 미세 조정합니다:
+
+```py
+>>> model.fit(
+... tf_train_dataset,
+... validation_data=tf_eval_dataset,
+... callbacks=callbacks,
+... epochs=num_epochs,
+... )
+```
+
+축하합니다! 모델을 미세 조정하고 🤗 Hub에 공유했습니다. 이제 추론에 사용할 수 있습니다!
+
+
+
+
+
+## 추론하기[[inference]]
+
+이제 모델을 미세 조정했으니 추론에 사용할 수 있습니다!
+
+추론할 이미지를 로드하세요:
+
+```py
+>>> image = ds[0]["image"]
+>>> image
+```
+
+
+
+
+
+
+추론을 위해 미세 조정한 모델을 시험해 보는 가장 간단한 방법은 [`pipeline`]에서 사용하는 것입니다. 모델을 사용하여 이미지 분할을 위한 `pipeline`을 인스턴스화하고 이미지를 전달합니다:
+
+```py
+>>> from transformers import pipeline
+
+>>> segmenter = pipeline("image-segmentation", model="my_awesome_seg_model")
+>>> segmenter(image)
+[{'score': None,
+ 'label': 'wall',
+ 'mask': },
+ {'score': None,
+ 'label': 'sky',
+ 'mask': },
+ {'score': None,
+ 'label': 'floor',
+ 'mask': },
+ {'score': None,
+ 'label': 'ceiling',
+ 'mask': },
+ {'score': None,
+ 'label': 'bed ',
+ 'mask': },
+ {'score': None,
+ 'label': 'windowpane',
+ 'mask': },
+ {'score': None,
+ 'label': 'cabinet',
+ 'mask': },
+ {'score': None,
+ 'label': 'chair',
+ 'mask': },
+ {'score': None,
+ 'label': 'armchair',
+ 'mask': }]
+```
+원하는 경우 `pipeline`의 결과를 수동으로 복제할 수도 있습니다. 이미지 프로세서로 이미지를 처리하고 `pixel_values`을 GPU에 배치합니다:
+
+```py
+>>> device = torch.device("cuda" if torch.cuda.is_available() else "cpu") # 가능하다면 GPU를 사용하고, 그렇지 않다면 CPU를 사용하세요
+>>> encoding = image_processor(image, return_tensors="pt")
+>>> pixel_values = encoding.pixel_values.to(device)
+```
+
+모델에 입력을 전달하고 `logits`를 반환합니다:
+
+```py
+>>> outputs = model(pixel_values=pixel_values)
+>>> logits = outputs.logits.cpu()
+```
+그런 다음 로짓의 크기를 원본 이미지 크기로 다시 조정합니다:
+
+```py
+>>> upsampled_logits = nn.functional.interpolate(
+... logits,
+... size=image.size[::-1],
+... mode="bilinear",
+... align_corners=False,
+... )
+
+>>> pred_seg = upsampled_logits.argmax(dim=1)[0]
+```
+
+
+
+
+
+
+이미지 프로세서를 로드하여 이미지를 전처리하고 입력을 TensorFlow 텐서로 반환합니다:
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("MariaK/scene_segmentation")
+>>> inputs = image_processor(image, return_tensors="tf")
+```
+
+모델에 입력을 전달하고 `logits`를 반환합니다:
+
+```py
+>>> from transformers import TFAutoModelForSemanticSegmentation
+
+>>> model = TFAutoModelForSemanticSegmentation.from_pretrained("MariaK/scene_segmentation")
+>>> logits = model(**inputs).logits
+```
+
+그런 다음 로그를 원본 이미지 크기로 재조정하고 클래스 차원에 argmax를 적용합니다:
+
+```py
+>>> logits = tf.transpose(logits, [0, 2, 3, 1])
+
+>>> upsampled_logits = tf.image.resize(
+... logits,
+... # `image.size`가 너비와 높이를 반환하기 때문에 `image`의 모양을 반전시킵니다
+... image.size[::-1],
+... )
+
+>>> pred_seg = tf.math.argmax(upsampled_logits, axis=-1)[0]
+```
+
+
+
+
+결과를 시각화하려면 [dataset color palette](https://github.com/tensorflow/models/blob/3f1ca33afe3c1631b733ea7e40c294273b9e406d/research/deeplab/utils/get_dataset_colormap.py#L51)를 각 클래스를 RGB 값에 매핑하는 `ade_palette()`로 로드합니다. 그런 다음 이미지와 예측된 분할 지도(segmentation map)을 결합하여 구성할 수 있습니다:
+
+```py
+>>> import matplotlib.pyplot as plt
+>>> import numpy as np
+
+>>> color_seg = np.zeros((pred_seg.shape[0], pred_seg.shape[1], 3), dtype=np.uint8)
+>>> palette = np.array(ade_palette())
+>>> for label, color in enumerate(palette):
+... color_seg[pred_seg == label, :] = color
+>>> color_seg = color_seg[..., ::-1] # BGR로 변환
+
+>>> img = np.array(image) * 0.5 + color_seg * 0.5 # 분할 지도으로 이미지 구성
+>>> img = img.astype(np.uint8)
+
+>>> plt.figure(figsize=(15, 10))
+>>> plt.imshow(img)
+>>> plt.show()
+```
+
+
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/text-classification)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에, 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+Hugging Face 계정에 로그인하여 모델을 업로드하고 커뮤니티에 공유하는 것을 권장합니다. 메시지가 표시되면, 토큰을 입력하여 로그인하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## IMDb 데이터셋 가져오기[[load-imdb-dataset]]
+
+먼저 🤗 Datasets 라이브러리에서 IMDb 데이터셋을 가져옵니다:
+
+```py
+>>> from datasets import load_dataset
+
+>>> imdb = load_dataset("imdb")
+```
+
+그런 다음 예시를 살펴봅시다:
+
+```py
+>>> imdb["test"][0]
+{
+ "label": 0,
+ "text": "I love sci-fi and am willing to put up with a lot. Sci-fi movies/TV are usually underfunded, under-appreciated and misunderstood. I tried to like this, I really did, but it is to good TV sci-fi as Babylon 5 is to Star Trek (the original). Silly prosthetics, cheap cardboard sets, stilted dialogues, CG that doesn't match the background, and painfully one-dimensional characters cannot be overcome with a 'sci-fi' setting. (I'm sure there are those of you out there who think Babylon 5 is good sci-fi TV. It's not. It's clichéd and uninspiring.) While US viewers might like emotion and character development, sci-fi is a genre that does not take itself seriously (cf. Star Trek). It may treat important issues, yet not as a serious philosophy. It's really difficult to care about the characters here as they are not simply foolish, just missing a spark of life. Their actions and reactions are wooden and predictable, often painful to watch. The makers of Earth KNOW it's rubbish as they have to always say \"Gene Roddenberry's Earth...\" otherwise people would not continue watching. Roddenberry's ashes must be turning in their orbit as this dull, cheap, poorly edited (watching it without advert breaks really brings this home) trudging Trabant of a show lumbers into space. Spoiler. So, kill off a main character. And then bring him back as another actor. Jeeez! Dallas all over again.",
+}
+```
+
+이 데이터셋에는 두 가지 필드가 있습니다:
+
+- `text`: 영화 리뷰 텍스트
+- `label`: `0`은 부정적인 리뷰, `1`은 긍정적인 리뷰를 나타냅니다.
+
+## 전처리[[preprocess]]
+
+다음 단계는 DistilBERT 토크나이저를 가져와서 `text` 필드를 전처리하는 것입니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+`text`를 토큰화하고 시퀀스가 DistilBERT의 최대 입력 길이보다 길지 않도록 자르기 위한 전처리 함수를 생성하세요:
+
+```py
+>>> def preprocess_function(examples):
+... return tokenizer(examples["text"], truncation=True)
+```
+
+전체 데이터셋에 전처리 함수를 적용하려면, 🤗 Datasets [`~datasets.Dataset.map`] 함수를 사용하세요. 데이터셋의 여러 요소를 한 번에 처리하기 위해 `batched=True`로 설정함으로써 데이터셋 `map`를 더 빠르게 처리할 수 있습니다:
+
+```py
+tokenized_imdb = imdb.map(preprocess_function, batched=True)
+```
+
+이제 [`DataCollatorWithPadding`]를 사용하여 예제 배치를 만들어봅시다. 데이터셋 전체를 최대 길이로 패딩하는 대신, *동적 패딩*을 사용하여 배치에서 가장 긴 길이에 맞게 문장을 패딩하는 것이 효율적입니다.
+
+
+
+```py
+>>> from transformers import DataCollatorWithPadding
+
+>>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
+```
+
+
+```py
+>>> from transformers import DataCollatorWithPadding
+
+>>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer, return_tensors="tf")
+```
+
+
+
+## 평가하기[[evaluate]]
+
+훈련 중 모델의 성능을 평가하기 위해 메트릭을 포함하는 것이 유용합니다. 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리를 사용하여 빠르게 평가 방법을 로드할 수 있습니다. 이 작업에서는 [accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) 메트릭을 가져옵니다. (메트릭을 가져오고 계산하는 방법에 대해서는 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하세요):
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+그런 다음 `compute_metrics` 함수를 만들어서 예측과 레이블을 계산하여 정확도를 계산하도록 [`~evaluate.EvaluationModule.compute`]를 호출합니다:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... predictions = np.argmax(predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=labels)
+```
+
+이제 `compute_metrics` 함수는 준비되었고, 훈련 과정을 설정할 때 다시 살펴볼 예정입니다.
+
+## 훈련[[train]]
+
+모델을 훈련하기 전에, `id2label`와 `label2id`를 사용하여 예상되는 id와 레이블의 맵을 생성하세요:
+
+```py
+>>> id2label = {0: "NEGATIVE", 1: "POSITIVE"}
+>>> label2id = {"NEGATIVE": 0, "POSITIVE": 1}
+```
+
+
+
+
+
+[`Trainer`]를 사용하여 모델을 파인 튜닝하는 방법에 익숙하지 않은 경우, [여기](../training#train-with-pytorch-trainer)의 기본 튜토리얼을 확인하세요!
+
+
+
+이제 모델을 훈련시킬 준비가 되었습니다! [`AutoModelForSequenceClassification`]로 DistilBERT를 가쳐오고 예상되는 레이블 수와 레이블 매핑을 지정하세요:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForSequenceClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=2, id2label=id2label, label2id=label2id
+... )
+```
+
+이제 세 단계만 거치면 끝입니다:
+
+1. [`TrainingArguments`]에서 하이퍼파라미터를 정의하세요. `output_dir`는 모델을 저장할 위치를 지정하는 유일한 파라미터입니다. 이 모델을 Hub에 업로드하기 위해 `push_to_hub=True`를 설정합니다. (모델을 업로드하기 위해 Hugging Face에 로그인해야합니다.) 각 에폭이 끝날 때마다, [`Trainer`]는 정확도를 평가하고 훈련 체크포인트를 저장합니다.
+2. [`Trainer`]에 훈련 인수와 모델, 데이터셋, 토크나이저, 데이터 수집기 및 `compute_metrics` 함수를 전달하세요.
+3. [`~Trainer.train`]를 호출하여 모델은 파인 튜닝하세요.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_model",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=2,
+... weight_decay=0.01,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... load_best_model_at_end=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_imdb["train"],
+... eval_dataset=tokenized_imdb["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+
+
+[`Trainer`]는 `tokenizer`를 전달하면 기본적으로 동적 매핑을 적용합니다. 이 경우, 명시적으로 데이터 수집기를 지정할 필요가 없습니다.
+
+
+
+훈련이 완료되면, [`~transformers.Trainer.push_to_hub`] 메소드를 사용하여 모델을 Hub에 공유할 수 있습니다.
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras를 사용하여 모델을 파인 튜닝하는 방법에 익숙하지 않은 경우, [여기](../training#train-a-tensorflow-model-with-keras)의 기본 튜토리얼을 확인하세요!
+
+
+TensorFlow에서 모델을 파인 튜닝하려면, 먼저 옵티마이저 함수와 학습률 스케쥴, 그리고 일부 훈련 하이퍼파라미터를 설정해야 합니다:
+
+```py
+>>> from transformers import create_optimizer
+>>> import tensorflow as tf
+
+>>> batch_size = 16
+>>> num_epochs = 5
+>>> batches_per_epoch = len(tokenized_imdb["train"]) // batch_size
+>>> total_train_steps = int(batches_per_epoch * num_epochs)
+>>> optimizer, schedule = create_optimizer(init_lr=2e-5, num_warmup_steps=0, num_train_steps=total_train_steps)
+```
+
+그런 다음 [`TFAutoModelForSequenceClassification`]을 사용하여 DistilBERT를 로드하고, 예상되는 레이블 수와 레이블 매핑을 로드할 수 있습니다:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=2, id2label=id2label, label2id=label2id
+... )
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`]을 사용하여 데이터셋을 `tf.data.Dataset` 형식으로 변환합니다:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_imdb["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_imdb["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method)를 사용하여 훈련할 모델을 구성합니다:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+훈련을 시작하기 전에 설정해야할 마지막 두 가지는 예측에서 정확도를 계산하고, 모델을 Hub에 업로드할 방법을 제공하는 것입니다. 모두 [Keras callbacks](../main_classes/keras_callbacks)를 사용하여 수행됩니다.
+
+[`~transformers.KerasMetricCallback`]에 `compute_metrics`를 전달하여 정확도를 높입니다.
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+[`~transformers.PushToHubCallback`]에서 모델과 토크나이저를 업로드할 위치를 지정합니다:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_model",
+... tokenizer=tokenizer,
+... )
+```
+
+그런 다음 콜백을 함께 묶습니다:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+드디어, 모델 훈련을 시작할 준비가 되었습니다! [`fit`](https://keras.io/api/models/model_training_apis/#fit-method)에 훈련 데이터셋, 검증 데이터셋, 에폭의 수 및 콜백을 전달하여 파인 튜닝합니다:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3, callbacks=callbacks)
+```
+
+훈련이 완료되면, 모델이 자동으로 Hub에 업로드되어 모든 사람이 사용할 수 있습니다!
+
+
+
+
+
+텍스트 분류를 위한 모델을 파인 튜닝하는 자세한 예제는 다음 [PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification.ipynb) 또는 [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification-tf.ipynb)를 참조하세요.
+
+
+
+## 추론[[inference]]
+
+좋아요, 이제 모델을 파인 튜닝했으니 추론에 사용할 수 있습니다!
+
+추론을 수행하고자 하는 텍스트를 가져와봅시다:
+
+```py
+>>> text = "This was a masterpiece. Not completely faithful to the books, but enthralling from beginning to end. Might be my favorite of the three."
+```
+
+파인 튜닝된 모델로 추론을 시도하는 가장 간단한 방법은 [`pipeline`]를 사용하는 것입니다. 모델로 감정 분석을 위한 `pipeline`을 인스턴스화하고, 텍스트를 전달해보세요:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("sentiment-analysis", model="stevhliu/my_awesome_model")
+>>> classifier(text)
+[{'label': 'POSITIVE', 'score': 0.9994940757751465}]
+```
+
+원한다면, `pipeline`의 결과를 수동으로 복제할 수도 있습니다.
+
+
+
+텍스트를 토큰화하고 PyTorch 텐서를 반환합니다.
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_model")
+>>> inputs = tokenizer(text, return_tensors="pt")
+```
+
+입력을 모델에 전달하고 `logits`을 반환합니다:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("stevhliu/my_awesome_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+가장 높은 확률을 가진 클래스를 모델의 `id2label` 매핑을 사용하여 텍스트 레이블로 변환합니다:
+
+```py
+>>> predicted_class_id = logits.argmax().item()
+>>> model.config.id2label[predicted_class_id]
+'POSITIVE'
+```
+
+
+텍스트를 토큰화하고 TensorFlow 텐서를 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_model")
+>>> inputs = tokenizer(text, return_tensors="tf")
+```
+
+입력값을 모델에 전달하고 `logits`을 반환합니다:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("stevhliu/my_awesome_model")
+>>> logits = model(**inputs).logits
+```
+
+가장 높은 확률을 가진 클래스를 모델의 `id2label` 매핑을 사용하여 텍스트 레이블로 변환합니다:
+
+```py
+>>> predicted_class_id = int(tf.math.argmax(logits, axis=-1)[0])
+>>> model.config.id2label[predicted_class_id]
+'POSITIVE'
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/summarization.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/summarization.md
new file mode 100644
index 0000000000000000000000000000000000000000..a2b2b1fbc95498baaeb02b00b39894d60e801370
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/summarization.md
@@ -0,0 +1,413 @@
+
+
+# 요약[[summarization]]
+
+[[open-in-colab]]
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/summarization)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate rouge_score
+```
+
+Hugging Face 계정에 로그인하면 모델을 업로드하고 커뮤니티에 공유할 수 있습니다.
+토큰을 입력하여 로그인하세요.
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## BillSum 데이터셋 가져오기[[load-billsum-dataset]]
+
+🤗 Datasets 라이브러리에서 BillSum 데이터셋의 작은 버전인 캘리포니아 주 법안 하위 집합을 가져오세요:
+
+```py
+>>> from datasets import load_dataset
+
+>>> billsum = load_dataset("billsum", split="ca_test")
+```
+
+[`~datasets.Dataset.train_test_split`] 메소드로 데이터셋을 학습용와 테스트용으로 나누세요:
+
+```py
+>>> billsum = billsum.train_test_split(test_size=0.2)
+```
+
+그런 다음 예시를 하나 살펴보세요:
+
+```py
+>>> billsum["train"][0]
+{'summary': 'Existing law authorizes state agencies to enter into contracts for the acquisition of goods or services upon approval by the Department of General Services. Existing law sets forth various requirements and prohibitions for those contracts, including, but not limited to, a prohibition on entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between spouses and domestic partners or same-sex and different-sex couples in the provision of benefits. Existing law provides that a contract entered into in violation of those requirements and prohibitions is void and authorizes the state or any person acting on behalf of the state to bring a civil action seeking a determination that a contract is in violation and therefore void. Under existing law, a willful violation of those requirements and prohibitions is a misdemeanor.\nThis bill would also prohibit a state agency from entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between employees on the basis of gender identity in the provision of benefits, as specified. By expanding the scope of a crime, this bill would impose a state-mandated local program.\nThe California Constitution requires the state to reimburse local agencies and school districts for certain costs mandated by the state. Statutory provisions establish procedures for making that reimbursement.\nThis bill would provide that no reimbursement is required by this act for a specified reason.',
+ 'text': 'The people of the State of California do enact as follows:\n\n\nSECTION 1.\nSection 10295.35 is added to the Public Contract Code, to read:\n10295.35.\n(a) (1) Notwithstanding any other law, a state agency shall not enter into any contract for the acquisition of goods or services in the amount of one hundred thousand dollars ($100,000) or more with a contractor that, in the provision of benefits, discriminates between employees on the basis of an employee’s or dependent’s actual or perceived gender identity, including, but not limited to, the employee’s or dependent’s identification as transgender.\n(2) For purposes of this section, “contract” includes contracts with a cumulative amount of one hundred thousand dollars ($100,000) or more per contractor in each fiscal year.\n(3) For purposes of this section, an employee health plan is discriminatory if the plan is not consistent with Section 1365.5 of the Health and Safety Code and Section 10140 of the Insurance Code.\n(4) The requirements of this section shall apply only to those portions of a contractor’s operations that occur under any of the following conditions:\n(A) Within the state.\n(B) On real property outside the state if the property is owned by the state or if the state has a right to occupy the property, and if the contractor’s presence at that location is connected to a contract with the state.\n(C) Elsewhere in the United States where work related to a state contract is being performed.\n(b) Contractors shall treat as confidential, to the maximum extent allowed by law or by the requirement of the contractor’s insurance provider, any request by an employee or applicant for employment benefits or any documentation of eligibility for benefits submitted by an employee or applicant for employment.\n(c) After taking all reasonable measures to find a contractor that complies with this section, as determined by the state agency, the requirements of this section may be waived under any of the following circumstances:\n(1) There is only one prospective contractor willing to enter into a specific contract with the state agency.\n(2) The contract is necessary to respond to an emergency, as determined by the state agency, that endangers the public health, welfare, or safety, or the contract is necessary for the provision of essential services, and no entity that complies with the requirements of this section capable of responding to the emergency is immediately available.\n(3) The requirements of this section violate, or are inconsistent with, the terms or conditions of a grant, subvention, or agreement, if the agency has made a good faith attempt to change the terms or conditions of any grant, subvention, or agreement to authorize application of this section.\n(4) The contractor is providing wholesale or bulk water, power, or natural gas, the conveyance or transmission of the same, or ancillary services, as required for ensuring reliable services in accordance with good utility practice, if the purchase of the same cannot practically be accomplished through the standard competitive bidding procedures and the contractor is not providing direct retail services to end users.\n(d) (1) A contractor shall not be deemed to discriminate in the provision of benefits if the contractor, in providing the benefits, pays the actual costs incurred in obtaining the benefit.\n(2) If a contractor is unable to provide a certain benefit, despite taking reasonable measures to do so, the contractor shall not be deemed to discriminate in the provision of benefits.\n(e) (1) Every contract subject to this chapter shall contain a statement by which the contractor certifies that the contractor is in compliance with this section.\n(2) The department or other contracting agency shall enforce this section pursuant to its existing enforcement powers.\n(3) (A) If a contractor falsely certifies that it is in compliance with this section, the contract with that contractor shall be subject to Article 9 (commencing with Section 10420), unless, within a time period specified by the department or other contracting agency, the contractor provides to the department or agency proof that it has complied, or is in the process of complying, with this section.\n(B) The application of the remedies or penalties contained in Article 9 (commencing with Section 10420) to a contract subject to this chapter shall not preclude the application of any existing remedies otherwise available to the department or other contracting agency under its existing enforcement powers.\n(f) Nothing in this section is intended to regulate the contracting practices of any local jurisdiction.\n(g) This section shall be construed so as not to conflict with applicable federal laws, rules, or regulations. In the event that a court or agency of competent jurisdiction holds that federal law, rule, or regulation invalidates any clause, sentence, paragraph, or section of this code or the application thereof to any person or circumstances, it is the intent of the state that the court or agency sever that clause, sentence, paragraph, or section so that the remainder of this section shall remain in effect.\nSEC. 2.\nSection 10295.35 of the Public Contract Code shall not be construed to create any new enforcement authority or responsibility in the Department of General Services or any other contracting agency.\nSEC. 3.\nNo reimbursement is required by this act pursuant to Section 6 of Article XIII\u2009B of the California Constitution because the only costs that may be incurred by a local agency or school district will be incurred because this act creates a new crime or infraction, eliminates a crime or infraction, or changes the penalty for a crime or infraction, within the meaning of Section 17556 of the Government Code, or changes the definition of a crime within the meaning of Section 6 of Article XIII\u2009B of the California Constitution.',
+ 'title': 'An act to add Section 10295.35 to the Public Contract Code, relating to public contracts.'}
+```
+
+여기서 다음 두 개의 필드를 사용하게 됩니다:
+
+- `text`: 모델의 입력이 될 법안 텍스트입니다.
+- `summary`: `text`의 간략한 버전으로 모델의 타겟이 됩니다.
+
+## 전처리[[preprocess]]
+
+다음으로 `text`와 `summary`를 처리하기 위한 T5 토크나이저를 가져옵니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> checkpoint = "google-t5/t5-small"
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+```
+
+생성하려는 전처리 함수는 아래 조건을 만족해야 합니다:
+
+1. 입력 앞에 프롬프트를 붙여 T5가 요약 작업임을 인식할 수 있도록 합니다. 여러 NLP 작업을 수행할 수 있는 일부 모델은 특정 작업에 대한 프롬프트가 필요합니다.
+2. 레이블을 토큰화할 때 `text_target` 인수를 사용합니다.
+3. `max_length` 매개변수로 설정된 최대 길이를 넘지 않도록 긴 시퀀스를 잘라냅니다.
+
+```py
+>>> prefix = "summarize: "
+
+
+>>> def preprocess_function(examples):
+... inputs = [prefix + doc for doc in examples["text"]]
+... model_inputs = tokenizer(inputs, max_length=1024, truncation=True)
+
+... labels = tokenizer(text_target=examples["summary"], max_length=128, truncation=True)
+
+... model_inputs["labels"] = labels["input_ids"]
+... return model_inputs
+```
+
+전체 데이터셋에 전처리 함수를 적용하려면 🤗 Datasets의 [`~datasets.Dataset.map`] 메소드를 사용하세요.
+`batched=True`로 설정하여 데이터셋의 여러 요소를 한 번에 처리하면 `map` 함수의 속도를 높일 수 있습니다.
+
+```py
+>>> tokenized_billsum = billsum.map(preprocess_function, batched=True)
+```
+
+이제 [`DataCollatorForSeq2Seq`]를 사용하여 예제 배치를 만드세요.
+전체 데이터셋을 최대 길이로 패딩하는 것보다 배치마다 가장 긴 문장 길이에 맞춰 *동적 패딩*하는 것이 더 효율적입니다.
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint)
+```
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint, return_tensors="tf")
+```
+
+
+
+## 평가[[evaluate]]
+
+학습 중에 평가 지표를 포함하면 모델의 성능을 평가하는 데 도움이 되는 경우가 많습니다.
+🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리를 사용하면 평가 방법을 빠르게 불러올 수 있습니다.
+이 작업에서는 [ROUGE](https://huggingface.co/spaces/evaluate-metric/rouge) 평가 지표를 가져옵니다.
+(평가 지표를 불러오고 계산하는 방법은 🤗 Evaluate [둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하세요.)
+
+```py
+>>> import evaluate
+
+>>> rouge = evaluate.load("rouge")
+```
+
+그런 다음 예측값과 레이블을 [`~evaluate.EvaluationModule.compute`]에 전달하여 ROUGE 지표를 계산하는 함수를 만듭니다:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... decoded_preds = tokenizer.batch_decode(predictions, skip_special_tokens=True)
+... labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
+... decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+... result = rouge.compute(predictions=decoded_preds, references=decoded_labels, use_stemmer=True)
+
+... prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in predictions]
+... result["gen_len"] = np.mean(prediction_lens)
+
+... return {k: round(v, 4) for k, v in result.items()}
+```
+
+이제 `compute_metrics` 함수를 사용할 준비가 되었으며, 학습을 설정할 때 이 함수로 되돌아올 것입니다.
+
+## 학습[[train]]
+
+
+
+
+
+모델을 [`Trainer`]로 파인튜닝 하는 것이 익숙하지 않다면, [여기](../training#train-with-pytorch-trainer)에서 기본 튜토리얼을 확인해보세요!
+
+
+
+이제 모델 학습을 시작할 준비가 되었습니다! [`AutoModelForSeq2SeqLM`]로 T5를 가져오세요:
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM, Seq2SeqTrainingArguments, Seq2SeqTrainer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+이제 세 단계만 남았습니다:
+
+1. [`Seq2SeqTrainingArguments`]에서 학습 하이퍼파라미터를 정의하세요.
+유일한 필수 매개변수는 모델을 저장할 위치를 지정하는 `output_dir`입니다.
+`push_to_hub=True`를 설정하여 이 모델을 Hub에 푸시할 수 있습니다(모델을 업로드하려면 Hugging Face에 로그인해야 합니다.)
+[`Trainer`]는 각 에폭이 끝날 때마다 ROUGE 지표를 평가하고 학습 체크포인트를 저장합니다.
+2. 모델, 데이터셋, 토크나이저, 데이터 콜레이터 및 `compute_metrics` 함수와 함께 학습 인수를 [`Seq2SeqTrainer`]에 전달하세요.
+3. [`~Trainer.train`]을 호출하여 모델을 파인튜닝하세요.
+
+```py
+>>> training_args = Seq2SeqTrainingArguments(
+... output_dir="my_awesome_billsum_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... weight_decay=0.01,
+... save_total_limit=3,
+... num_train_epochs=4,
+... predict_with_generate=True,
+... fp16=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Seq2SeqTrainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_billsum["train"],
+... eval_dataset=tokenized_billsum["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+학습이 완료되면, 누구나 모델을 사용할 수 있도록 [`~transformers.Trainer.push_to_hub`] 메소드로 Hub에 공유합니다:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras로 모델 파인튜닝을 하는 것이 익숙하지 않다면, [여기](../training#train-a-tensorflow-model-with-keras)에서 기본적인 튜토리얼을 확인하세요!
+
+
+TensorFlow에서 모델을 파인튜닝하려면, 먼저 옵티마이저, 학습률 스케줄 그리고 몇 가지 학습 하이퍼파라미터를 설정하세요:
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+그런 다음 [`TFAutoModelForSeq2SeqLM`]을 사용하여 T5를 가져오세요:
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`]을 사용하여 데이터셋을 `tf.data.Dataset` 형식으로 변환하세요:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_billsum["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... tokenized_billsum["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method)을 사용하여 모델을 학습할 수 있도록 구성하세요:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+학습을 시작하기 전에 설정해야 할 마지막 두 가지는 예측에서 ROUGE 점수를 계산하고 모델을 Hub에 푸시하는 방법을 제공하는 것입니다.
+두 작업 모두 [Keras callbacks](../main_classes/keras_callbacks)으로 수행할 수 있습니다.
+
+[`~transformers.KerasMetricCallback`]에 `compute_metrics` 함수를 전달하세요:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+[`~transformers.PushToHubCallback`]에서 모델과 토크나이저를 푸시할 위치를 지정하세요:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_billsum_model",
+... tokenizer=tokenizer,
+... )
+```
+
+그런 다음 콜백을 번들로 묶어줍니다:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+드디어 모델 학습을 시작할 준비가 되었습니다!
+학습 및 검증 데이터셋, 에폭 수 및 콜백과 함께 [`fit`](https://keras.io/api/models/model_training_apis/#fit-method)을 호출하여 모델을 파인튜닝하세요.
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=callbacks)
+```
+
+학습이 완료되면 모델이 자동으로 Hub에 업로드되어 누구나 사용할 수 있게 됩니다!
+
+
+
+
+
+요약을 위해 모델을 파인튜닝하는 방법에 대한 더 자세한 예제를 보려면 [PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization.ipynb)
+또는 [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization-tf.ipynb)을 참고하세요.
+
+
+
+## 추론[[inference]]
+
+좋아요, 이제 모델을 파인튜닝했으니 추론에 사용할 수 있습니다!
+
+요약할 텍스트를 작성해보세요. T5의 경우 작업에 따라 입력 앞에 접두사를 붙여야 합니다. 요약의 경우, 아래와 같은 접두사를 입력 앞에 붙여야 합니다:
+
+```py
+>>> text = "summarize: The Inflation Reduction Act lowers prescription drug costs, health care costs, and energy costs. It's the most aggressive action on tackling the climate crisis in American history, which will lift up American workers and create good-paying, union jobs across the country. It'll lower the deficit and ask the ultra-wealthy and corporations to pay their fair share. And no one making under $400,000 per year will pay a penny more in taxes."
+```
+
+추론을 위해 파인튜닝한 모델을 시험해 보는 가장 간단한 방법은 [`pipeline`]에서 사용하는 것입니다.
+모델을 사용하여 요약을 수행할 [`pipeline`]을 인스턴스화하고 텍스트를 전달하세요:
+
+```py
+>>> from transformers import pipeline
+
+>>> summarizer = pipeline("summarization", model="stevhliu/my_awesome_billsum_model")
+>>> summarizer(text)
+[{"summary_text": "The Inflation Reduction Act lowers prescription drug costs, health care costs, and energy costs. It's the most aggressive action on tackling the climate crisis in American history, which will lift up American workers and create good-paying, union jobs across the country."}]
+```
+
+원한다면 수동으로 다음과 같은 작업을 수행하여 [`pipeline`]의 결과와 동일한 결과를 얻을 수 있습니다:
+
+
+
+
+텍스트를 토크나이즈하고 `input_ids`를 PyTorch 텐서로 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> inputs = tokenizer(text, return_tensors="pt").input_ids
+```
+
+요약문을 생성하려면 [`~generation.GenerationMixin.generate`] 메소드를 사용하세요.
+텍스트 생성에 대한 다양한 전략과 생성을 제어하기 위한 매개변수에 대한 자세한 내용은 [텍스트 생성](../main_classes/text_generation) API를 참조하세요.
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=False)
+```
+
+생성된 토큰 ID를 텍스트로 디코딩합니다:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'the inflation reduction act lowers prescription drug costs, health care costs, and energy costs. it's the most aggressive action on tackling the climate crisis in american history. it will ask the ultra-wealthy and corporations to pay their fair share.'
+```
+
+
+텍스트를 토크나이즈하고 `input_ids`를 TensorFlow 텐서로 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> inputs = tokenizer(text, return_tensors="tf").input_ids
+```
+
+요약문을 생성하려면 [`~transformers.generation_tf_utils.TFGenerationMixin.generate`] 메소드를 사용하세요.
+텍스트 생성에 대한 다양한 전략과 생성을 제어하기 위한 매개변수에 대한 자세한 내용은 [텍스트 생성](../main_classes/text_generation) API를 참조하세요.
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=False)
+```
+
+생성된 토큰 ID를 텍스트로 디코딩합니다:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'the inflation reduction act lowers prescription drug costs, health care costs, and energy costs. it's the most aggressive action on tackling the climate crisis in american history. it will ask the ultra-wealthy and corporations to pay their fair share.'
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/token_classification.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/token_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..a65503092cee1decc8e2983ba4df1bf5e1db6921
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/token_classification.md
@@ -0,0 +1,555 @@
+
+
+# 토큰 분류[[token-classification]]
+
+[[open-in-colab]]
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/token-classification)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에, 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate seqeval
+```
+
+Hugging Face 계정에 로그인하여 모델을 업로드하고 커뮤니티에 공유하는 것을 권장합니다. 메시지가 표시되면, 토큰을 입력하여 로그인하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## WNUT 17 데이터 세트 가져오기[[load-wnut-17-dataset]]
+
+먼저 🤗 Datasets 라이브러리에서 WNUT 17 데이터 세트를 가져옵니다:
+
+```py
+>>> from datasets import load_dataset
+
+>>> wnut = load_dataset("wnut_17")
+```
+
+다음 예제를 살펴보세요:
+
+```py
+>>> wnut["train"][0]
+{'id': '0',
+ 'ner_tags': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 7, 8, 8, 0, 7, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'tokens': ['@paulwalk', 'It', "'s", 'the', 'view', 'from', 'where', 'I', "'m", 'living', 'for', 'two', 'weeks', '.', 'Empire', 'State', 'Building', '=', 'ESB', '.', 'Pretty', 'bad', 'storm', 'here', 'last', 'evening', '.']
+}
+```
+
+`ner_tags`의 각 숫자는 개체를 나타냅니다. 숫자를 레이블 이름으로 변환하여 개체가 무엇인지 확인합니다:
+
+```py
+>>> label_list = wnut["train"].features[f"ner_tags"].feature.names
+>>> label_list
+[
+ "O",
+ "B-corporation",
+ "I-corporation",
+ "B-creative-work",
+ "I-creative-work",
+ "B-group",
+ "I-group",
+ "B-location",
+ "I-location",
+ "B-person",
+ "I-person",
+ "B-product",
+ "I-product",
+]
+```
+
+각 `ner_tag`의 앞에 붙은 문자는 개체의 토큰 위치를 나타냅니다:
+
+- `B-`는 개체의 시작을 나타냅니다.
+- `I-`는 토큰이 동일한 개체 내부에 포함되어 있음을 나타냅니다(예를 들어 `State` 토큰은 `Empire State Building`와 같은 개체의 일부입니다).
+- `0`는 토큰이 어떤 개체에도 해당하지 않음을 나타냅니다.
+
+## 전처리[[preprocess]]
+
+
+
+```py
+>>> from transformers import DataCollatorForTokenClassification
+
+>>> data_collator = DataCollatorForTokenClassification(tokenizer=tokenizer)
+```
+
+
+```py
+>>> from transformers import DataCollatorForTokenClassification
+
+>>> data_collator = DataCollatorForTokenClassification(tokenizer=tokenizer, return_tensors="tf")
+```
+
+
+
+## 평가[[evaluation]]
+
+훈련 중 모델의 성능을 평가하기 위해 평가 지표를 포함하는 것이 유용합니다. 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리를 사용하여 빠르게 평가 방법을 가져올 수 있습니다. 이 작업에서는 [seqeval](https://huggingface.co/spaces/evaluate-metric/seqeval) 평가 지표를 가져옵니다. (평가 지표를 가져오고 계산하는 방법에 대해서는 🤗 Evaluate [빠른 둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하세요). Seqeval은 실제로 정밀도, 재현률, F1 및 정확도와 같은 여러 점수를 산출합니다.
+
+```py
+>>> import evaluate
+
+>>> seqeval = evaluate.load("seqeval")
+```
+
+먼저 NER 레이블을 가져온 다음, [`~evaluate.EvaluationModule.compute`]에 실제 예측과 실제 레이블을 전달하여 점수를 계산하는 함수를 만듭니다:
+
+```py
+>>> import numpy as np
+
+>>> labels = [label_list[i] for i in example[f"ner_tags"]]
+
+
+>>> def compute_metrics(p):
+... predictions, labels = p
+... predictions = np.argmax(predictions, axis=2)
+
+... true_predictions = [
+... [label_list[p] for (p, l) in zip(prediction, label) if l != -100]
+... for prediction, label in zip(predictions, labels)
+... ]
+... true_labels = [
+... [label_list[l] for (p, l) in zip(prediction, label) if l != -100]
+... for prediction, label in zip(predictions, labels)
+... ]
+
+... results = seqeval.compute(predictions=true_predictions, references=true_labels)
+... return {
+... "precision": results["overall_precision"],
+... "recall": results["overall_recall"],
+... "f1": results["overall_f1"],
+... "accuracy": results["overall_accuracy"],
+... }
+```
+
+이제 `compute_metrics` 함수를 사용할 준비가 되었으며, 훈련을 설정하면 이 함수로 되돌아올 것입니다.
+
+## 훈련[[train]]
+
+모델을 훈련하기 전에, `id2label`와 `label2id`를 사용하여 예상되는 id와 레이블의 맵을 생성하세요:
+
+```py
+>>> id2label = {
+... 0: "O",
+... 1: "B-corporation",
+... 2: "I-corporation",
+... 3: "B-creative-work",
+... 4: "I-creative-work",
+... 5: "B-group",
+... 6: "I-group",
+... 7: "B-location",
+... 8: "I-location",
+... 9: "B-person",
+... 10: "I-person",
+... 11: "B-product",
+... 12: "I-product",
+... }
+>>> label2id = {
+... "O": 0,
+... "B-corporation": 1,
+... "I-corporation": 2,
+... "B-creative-work": 3,
+... "I-creative-work": 4,
+... "B-group": 5,
+... "I-group": 6,
+... "B-location": 7,
+... "I-location": 8,
+... "B-person": 9,
+... "I-person": 10,
+... "B-product": 11,
+... "I-product": 12,
+... }
+```
+
+
+
+
+
+[`Trainer`]를 사용하여 모델을 파인 튜닝하는 방법에 익숙하지 않은 경우, [여기](../training#train-with-pytorch-trainer)에서 기본 튜토리얼을 확인하세요!
+
+
+
+이제 모델을 훈련시킬 준비가 되었습니다! [`AutoModelForSequenceClassification`]로 DistilBERT를 가져오고 예상되는 레이블 수와 레이블 매핑을 지정하세요:
+
+```py
+>>> from transformers import AutoModelForTokenClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForTokenClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=13, id2label=id2label, label2id=label2id
+... )
+```
+
+이제 세 단계만 거치면 끝입니다:
+
+1. [`TrainingArguments`]에서 하이퍼파라미터를 정의하세요. `output_dir`는 모델을 저장할 위치를 지정하는 유일한 매개변수입니다. 이 모델을 허브에 업로드하기 위해 `push_to_hub=True`를 설정합니다(모델을 업로드하기 위해 Hugging Face에 로그인해야합니다.) 각 에폭이 끝날 때마다, [`Trainer`]는 seqeval 점수를 평가하고 훈련 체크포인트를 저장합니다.
+2. [`Trainer`]에 훈련 인수와 모델, 데이터 세트, 토크나이저, 데이터 콜레이터 및 `compute_metrics` 함수를 전달하세요.
+3. [`~Trainer.train`]를 호출하여 모델을 파인 튜닝하세요.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_wnut_model",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=2,
+... weight_decay=0.01,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... load_best_model_at_end=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_wnut["train"],
+... eval_dataset=tokenized_wnut["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면, [`~transformers.Trainer.push_to_hub`] 메소드를 사용하여 모델을 허브에 공유할 수 있습니다.
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras를 사용하여 모델을 파인 튜닝하는 방법에 익숙하지 않은 경우, [여기](../training#train-a-tensorflow-model-with-keras)의 기본 튜토리얼을 확인하세요!
+
+
+TensorFlow에서 모델을 파인 튜닝하려면, 먼저 옵티마이저 함수와 학습률 스케쥴, 그리고 일부 훈련 하이퍼파라미터를 설정해야 합니다:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_train_epochs = 3
+>>> num_train_steps = (len(tokenized_wnut["train"]) // batch_size) * num_train_epochs
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=2e-5,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=0.01,
+... num_warmup_steps=0,
+... )
+```
+
+그런 다음 [`TFAutoModelForSequenceClassification`]을 사용하여 DistilBERT를 가져오고, 예상되는 레이블 수와 레이블 매핑을 지정합니다:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=13, id2label=id2label, label2id=label2id
+... )
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`]을 사용하여 데이터 세트를 `tf.data.Dataset` 형식으로 변환합니다:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_wnut["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_wnut["validation"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method)를 사용하여 훈련할 모델을 구성합니다:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+훈련을 시작하기 전에 설정해야할 마지막 두 가지는 예측에서 seqeval 점수를 계산하고, 모델을 허브에 업로드할 방법을 제공하는 것입니다. 모두 [Keras callbacks](../main_classes/keras_callbacks)를 사용하여 수행됩니다.
+
+[`~transformers.KerasMetricCallback`]에 `compute_metrics` 함수를 전달하세요:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+[`~transformers.PushToHubCallback`]에서 모델과 토크나이저를 업로드할 위치를 지정합니다:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_wnut_model",
+... tokenizer=tokenizer,
+... )
+```
+
+그런 다음 콜백을 함께 묶습니다:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+드디어, 모델 훈련을 시작할 준비가 되었습니다! [`fit`](https://keras.io/api/models/model_training_apis/#fit-method)에 훈련 데이터 세트, 검증 데이터 세트, 에폭의 수 및 콜백을 전달하여 파인 튜닝합니다:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3, callbacks=callbacks)
+```
+
+훈련이 완료되면, 모델이 자동으로 허브에 업로드되어 누구나 사용할 수 있습니다!
+
+
+
+
+
+토큰 분류를 위한 모델을 파인 튜닝하는 자세한 예제는 다음
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification.ipynb)
+또는 [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification-tf.ipynb)를 참조하세요.
+
+
+
+## 추론[[inference]]
+
+좋아요, 이제 모델을 파인 튜닝했으니 추론에 사용할 수 있습니다!
+
+추론을 수행하고자 하는 텍스트를 가져와봅시다:
+
+```py
+>>> text = "The Golden State Warriors are an American professional basketball team based in San Francisco."
+```
+
+파인 튜닝된 모델로 추론을 시도하는 가장 간단한 방법은 [`pipeline`]를 사용하는 것입니다. 모델로 NER의 `pipeline`을 인스턴스화하고, 텍스트를 전달해보세요:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("ner", model="stevhliu/my_awesome_wnut_model")
+>>> classifier(text)
+[{'entity': 'B-location',
+ 'score': 0.42658573,
+ 'index': 2,
+ 'word': 'golden',
+ 'start': 4,
+ 'end': 10},
+ {'entity': 'I-location',
+ 'score': 0.35856336,
+ 'index': 3,
+ 'word': 'state',
+ 'start': 11,
+ 'end': 16},
+ {'entity': 'B-group',
+ 'score': 0.3064001,
+ 'index': 4,
+ 'word': 'warriors',
+ 'start': 17,
+ 'end': 25},
+ {'entity': 'B-location',
+ 'score': 0.65523505,
+ 'index': 13,
+ 'word': 'san',
+ 'start': 80,
+ 'end': 83},
+ {'entity': 'B-location',
+ 'score': 0.4668663,
+ 'index': 14,
+ 'word': 'francisco',
+ 'start': 84,
+ 'end': 93}]
+```
+
+원한다면, `pipeline`의 결과를 수동으로 복제할 수도 있습니다:
+
+
+
+텍스트를 토큰화하고 PyTorch 텐서를 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> inputs = tokenizer(text, return_tensors="pt")
+```
+
+입력을 모델에 전달하고 `logits`을 반환합니다:
+
+```py
+>>> from transformers import AutoModelForTokenClassification
+
+>>> model = AutoModelForTokenClassification.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+가장 높은 확률을 가진 클래스를 모델의 `id2label` 매핑을 사용하여 텍스트 레이블로 변환합니다:
+
+```py
+>>> predictions = torch.argmax(logits, dim=2)
+>>> predicted_token_class = [model.config.id2label[t.item()] for t in predictions[0]]
+>>> predicted_token_class
+['O',
+ 'O',
+ 'B-location',
+ 'I-location',
+ 'B-group',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'B-location',
+ 'B-location',
+ 'O',
+ 'O']
+```
+
+
+텍스트를 토큰화하고 TensorFlow 텐서를 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> inputs = tokenizer(text, return_tensors="tf")
+```
+
+입력값을 모델에 전달하고 `logits`을 반환합니다:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> logits = model(**inputs).logits
+```
+
+가장 높은 확률을 가진 클래스를 모델의 `id2label` 매핑을 사용하여 텍스트 레이블로 변환합니다:
+
+```py
+>>> predicted_token_class_ids = tf.math.argmax(logits, axis=-1)
+>>> predicted_token_class = [model.config.id2label[t] for t in predicted_token_class_ids[0].numpy().tolist()]
+>>> predicted_token_class
+['O',
+ 'O',
+ 'B-location',
+ 'I-location',
+ 'B-group',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'B-location',
+ 'B-location',
+ 'O',
+ 'O']
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/translation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/translation.md
new file mode 100644
index 0000000000000000000000000000000000000000..5b4eaaa6125a11b0167be3c45d8cc1d021846ec0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/translation.md
@@ -0,0 +1,407 @@
+
+
+# 번역[[translation]]
+
+[[open-in-colab]]
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/translation)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate sacrebleu
+```
+
+모델을 업로드하고 커뮤니티와 공유할 수 있도록 Hugging Face 계정에 로그인하는 것이 좋습니다. 새로운 창이 표시되면 토큰을 입력하여 로그인하세요.
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## OPUS Books 데이터세트 가져오기[[load-opus-books-dataset]]
+
+먼저 🤗 Datasets 라이브러리에서 [OPUS Books](https://huggingface.co/datasets/opus_books) 데이터세트의 영어-프랑스어 하위 집합을 가져오세요.
+
+```py
+>>> from datasets import load_dataset
+
+>>> books = load_dataset("opus_books", "en-fr")
+```
+
+데이터세트를 [`~datasets.Dataset.train_test_split`] 메서드를 사용하여 훈련 및 테스트 데이터로 분할하세요.
+
+```py
+>>> books = books["train"].train_test_split(test_size=0.2)
+```
+
+훈련 데이터에서 예시를 살펴볼까요?
+
+```py
+>>> books["train"][0]
+{'id': '90560',
+ 'translation': {'en': 'But this lofty plateau measured only a few fathoms, and soon we reentered Our Element.',
+ 'fr': 'Mais ce plateau élevé ne mesurait que quelques toises, et bientôt nous fûmes rentrés dans notre élément.'}}
+```
+
+반환된 딕셔너리의 `translation` 키가 텍스트의 영어, 프랑스어 버전을 포함하고 있는 것을 볼 수 있습니다.
+
+## 전처리[[preprocess]]
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint)
+```
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint, return_tensors="tf")
+```
+
+
+
+## 평가[[evalulate]]
+
+훈련 중에 메트릭을 포함하면 모델의 성능을 평가하는 데 도움이 됩니다. 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리로 평가 방법(evaluation method)을 빠르게 가져올 수 있습니다. 현재 태스크에 적합한 SacreBLEU 메트릭을 가져오세요. (메트릭을 가져오고 계산하는 방법에 대해 자세히 알아보려면 🤗 Evaluate [둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하세요):
+
+```py
+>>> import evaluate
+
+>>> metric = evaluate.load("sacrebleu")
+```
+
+그런 다음 [`~evaluate.EvaluationModule.compute`]에 예측값과 레이블을 전달하여 SacreBLEU 점수를 계산하는 함수를 생성하세요:
+
+```py
+>>> import numpy as np
+
+
+>>> def postprocess_text(preds, labels):
+... preds = [pred.strip() for pred in preds]
+... labels = [[label.strip()] for label in labels]
+
+... return preds, labels
+
+
+>>> def compute_metrics(eval_preds):
+... preds, labels = eval_preds
+... if isinstance(preds, tuple):
+... preds = preds[0]
+... decoded_preds = tokenizer.batch_decode(preds, skip_special_tokens=True)
+
+... labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
+... decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+... decoded_preds, decoded_labels = postprocess_text(decoded_preds, decoded_labels)
+
+... result = metric.compute(predictions=decoded_preds, references=decoded_labels)
+... result = {"bleu": result["score"]}
+
+... prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in preds]
+... result["gen_len"] = np.mean(prediction_lens)
+... result = {k: round(v, 4) for k, v in result.items()}
+... return result
+```
+
+이제 `compute_metrics` 함수는 준비되었고, 훈련 과정을 설정할 때 다시 살펴볼 예정입니다.
+
+## 훈련[[train]]
+
+
+
+
+
+[`Trainer`]로 모델을 파인튜닝하는 방법에 익숙하지 않다면 [여기](../training#train-with-pytorch-trainer)에서 기본 튜토리얼을 살펴보시기 바랍니다!
+
+
+
+모델을 훈련시킬 준비가 되었군요! [`AutoModelForSeq2SeqLM`]으로 T5를 로드하세요:
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM, Seq2SeqTrainingArguments, Seq2SeqTrainer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+이제 세 단계만 거치면 끝입니다:
+
+1. [`Seq2SeqTrainingArguments`]에서 훈련 하이퍼파라미터를 정의하세요. 유일한 필수 매개변수는 모델을 저장할 위치인 `output_dir`입니다. 모델을 Hub에 푸시하기 위해 `push_to_hub=True`로 설정하세요. (모델을 업로드하려면 Hugging Face에 로그인해야 합니다.) [`Trainer`]는 에폭이 끝날때마다 SacreBLEU 메트릭을 평가하고 훈련 체크포인트를 저장합니다.
+2. [`Seq2SeqTrainer`]에 훈련 인수를 전달하세요. 모델, 데이터 세트, 토크나이저, data collator 및 `compute_metrics` 함수도 덩달아 전달해야 합니다.
+3. [`~Trainer.train`]을 호출하여 모델을 파인튜닝하세요.
+
+```py
+>>> training_args = Seq2SeqTrainingArguments(
+... output_dir="my_awesome_opus_books_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... weight_decay=0.01,
+... save_total_limit=3,
+... num_train_epochs=2,
+... predict_with_generate=True,
+... fp16=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Seq2SeqTrainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_books["train"],
+... eval_dataset=tokenized_books["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+학습이 완료되면 [`~transformers.Trainer.push_to_hub`] 메서드로 모델을 Hub에 공유하세요. 이러면 누구나 모델을 사용할 수 있게 됩니다:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras로 모델을 파인튜닝하는 방법이 익숙하지 않다면, [여기](../training#train-a-tensorflow-model-with-keras)에서 기본 튜토리얼을 살펴보시기 바랍니다!
+
+
+TensorFlow에서 모델을 파인튜닝하려면 우선 optimizer 함수, 학습률 스케줄 등의 훈련 하이퍼파라미터를 설정하세요:
+
+```py
+>>> from transformers import AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+이제 [`TFAutoModelForSeq2SeqLM`]로 T5를 가져오세요:
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`]로 데이터 세트를 `tf.data.Dataset` 형식으로 변환하세요:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_books["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... tokenized_books["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+훈련하기 위해 [`compile`](https://keras.io/api/models/model_training_apis/#compile-method) 메서드로 모델을 구성하세요:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+훈련을 시작하기 전에 예측값으로부터 SacreBLEU 메트릭을 계산하는 방법과 모델을 Hub에 업로드하는 방법 두 가지를 미리 설정해둬야 합니다. 둘 다 [Keras callbacks](../main_classes/keras_callbacks)로 구현하세요.
+
+[`~transformers.KerasMetricCallback`]에 `compute_metrics` 함수를 전달하세요.
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+모델과 토크나이저를 업로드할 위치를 [`~transformers.PushToHubCallback`]에서 지정하세요:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_opus_books_model",
+... tokenizer=tokenizer,
+... )
+```
+
+이제 콜백들을 한데로 묶어주세요:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+드디어 모델을 훈련시킬 모든 준비를 마쳤군요! 이제 훈련 및 검증 데이터 세트에 [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) 메서드를 에폭 수와 만들어둔 콜백과 함께 호출하여 모델을 파인튜닝하세요:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=callbacks)
+```
+
+학습이 완료되면 모델이 자동으로 Hub에 업로드되고, 누구나 사용할 수 있게 됩니다!
+
+
+
+
+
+번역을 위해 모델을 파인튜닝하는 방법에 대한 보다 자세한 예제는 해당 [PyTorch 노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation.ipynb) 또는 [TensorFlow 노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation-tf.ipynb)을 참조하세요.
+
+
+
+## 추론[[inference]]
+
+좋아요, 이제 모델을 파인튜닝했으니 추론에 사용할 수 있습니다!
+
+다른 언어로 번역하고 싶은 텍스트를 써보세요. T5의 경우 원하는 태스크를 입력의 접두사로 추가해야 합니다. 예를 들어 영어에서 프랑스어로 번역하는 경우, 아래와 같은 접두사가 추가됩니다:
+
+```py
+>>> text = "translate English to French: Legumes share resources with nitrogen-fixing bacteria."
+```
+
+파인튜닝된 모델로 추론하기에 제일 간단한 방법은 [`pipeline`]을 사용하는 것입니다. 해당 모델로 번역 `pipeline`을 만든 뒤, 텍스트를 전달하세요:
+
+```py
+>>> from transformers import pipeline
+
+# Change `xx` to the language of the input and `yy` to the language of the desired output.
+# Examples: "en" for English, "fr" for French, "de" for German, "es" for Spanish, "zh" for Chinese, etc; translation_en_to_fr translates English to French
+# You can view all the lists of languages here - https://huggingface.co/languages
+>>> translator = pipeline("translation_xx_to_yy", model="my_awesome_opus_books_model")
+>>> translator(text)
+[{'translation_text': 'Legumes partagent des ressources avec des bactéries azotantes.'}]
+```
+
+원한다면 `pipeline`의 결과를 직접 복제할 수도 있습니다:
+
+
+
+텍스트를 토큰화하고 `input_ids`를 PyTorch 텐서로 반환하세요:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_opus_books_model")
+>>> inputs = tokenizer(text, return_tensors="pt").input_ids
+```
+
+[`~generation.GenerationMixin.generate`] 메서드로 번역을 생성하세요. 다양한 텍스트 생성 전략 및 생성을 제어하기 위한 매개변수에 대한 자세한 내용은 [Text Generation](../main_classes/text_generation) API를 살펴보시기 바랍니다.
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("my_awesome_opus_books_model")
+>>> outputs = model.generate(inputs, max_new_tokens=40, do_sample=True, top_k=30, top_p=0.95)
+```
+
+생성된 토큰 ID들을 다시 텍스트로 디코딩하세요:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'Les lignées partagent des ressources avec des bactéries enfixant l'azote.'
+```
+
+
+텍스트를 토큰화하고 `input_ids`를 TensorFlow 텐서로 반환하세요:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_opus_books_model")
+>>> inputs = tokenizer(text, return_tensors="tf").input_ids
+```
+
+[`~transformers.generation_tf_utils.TFGenerationMixin.generate`] 메서드로 번역을 생성하세요. 다양한 텍스트 생성 전략 및 생성을 제어하기 위한 매개변수에 대한 자세한 내용은 [Text Generation](../main_classes/text_generation) API를 살펴보시기 바랍니다.
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained("my_awesome_opus_books_model")
+>>> outputs = model.generate(inputs, max_new_tokens=40, do_sample=True, top_k=30, top_p=0.95)
+```
+
+생성된 토큰 ID들을 다시 텍스트로 디코딩하세요:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'Les lugumes partagent les ressources avec des bactéries fixatrices d'azote.'
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/video_classification.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/video_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..10569083c09f85f6db4e81f88bf78d73742a4702
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tasks/video_classification.md
@@ -0,0 +1,492 @@
+
+
+# 영상 분류 [[video-classification]]
+
+[[open-in-colab]]
+
+
+영상 분류는 영상 전체에 레이블 또는 클래스를 지정하는 작업입니다. 각 영상에는 하나의 클래스가 있을 것으로 예상됩니다. 영상 분류 모델은 영상을 입력으로 받아 어느 클래스에 속하는지에 대한 예측을 반환합니다. 이러한 모델은 영상이 어떤 내용인지 분류하는 데 사용될 수 있습니다. 영상 분류의 실제 응용 예는 피트니스 앱에서 유용한 동작 / 운동 인식 서비스가 있습니다. 이는 또한 시각 장애인이 이동할 때 보조하는데 사용될 수 있습니다
+
+이 가이드에서는 다음을 수행하는 방법을 보여줍니다:
+
+1. [UCF101](https://www.crcv.ucf.edu/data/UCF101.php) 데이터 세트의 하위 집합을 통해 [VideoMAE](https://huggingface.co/docs/transformers/main/en/model_doc/videomae) 모델을 미세 조정하기.
+2. 미세 조정한 모델을 추론에 사용하기.
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/video-classification)를 확인하는 것이 좋습니다.
+
+
+
+
+시작하기 전에 필요한 모든 라이브러리가 설치되었는지 확인하세요:
+```bash
+pip install -q pytorchvideo transformers evaluate
+```
+
+영상을 처리하고 준비하기 위해 [PyTorchVideo](https://pytorchvideo.org/)(이하 `pytorchvideo`)를 사용합니다.
+
+커뮤니티에 모델을 업로드하고 공유할 수 있도록 Hugging Face 계정에 로그인하는 것을 권장합니다. 프롬프트가 나타나면 토큰을 입력하여 로그인하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## UCF101 데이터셋 불러오기 [[load-ufc101-dataset]]
+
+[UCF-101](https://www.crcv.ucf.edu/data/UCF101.php) 데이터 세트의 하위 집합(subset)을 불러오는 것으로 시작할 수 있습니다. 전체 데이터 세트를 학습하는데 더 많은 시간을 할애하기 전에 데이터의 하위 집합을 불러와 모든 것이 잘 작동하는지 실험하고 확인할 수 있습니다.
+
+```py
+>>> from huggingface_hub import hf_hub_download
+
+>>> hf_dataset_identifier = "sayakpaul/ucf101-subset"
+>>> filename = "UCF101_subset.tar.gz"
+>>> file_path = hf_hub_download(repo_id=hf_dataset_identifier, filename=filename, repo_type="dataset")
+```
+
+데이터 세트의 하위 집합이 다운로드 되면, 압축된 파일의 압축을 해제해야 합니다:
+```py
+>>> import tarfile
+
+>>> with tarfile.open(file_path) as t:
+... t.extractall(".")
+```
+
+전체 데이터 세트는 다음과 같이 구성되어 있습니다.
+
+```bash
+UCF101_subset/
+ train/
+ BandMarching/
+ video_1.mp4
+ video_2.mp4
+ ...
+ Archery
+ video_1.mp4
+ video_2.mp4
+ ...
+ ...
+ val/
+ BandMarching/
+ video_1.mp4
+ video_2.mp4
+ ...
+ Archery
+ video_1.mp4
+ video_2.mp4
+ ...
+ ...
+ test/
+ BandMarching/
+ video_1.mp4
+ video_2.mp4
+ ...
+ Archery
+ video_1.mp4
+ video_2.mp4
+ ...
+ ...
+```
+
+
+정렬된 영상의 경로는 다음과 같습니다:
+
+```bash
+...
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g07_c04.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g07_c06.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g08_c01.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g09_c02.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g09_c06.avi'
+...
+```
+
+동일한 그룹/장면에 속하는 영상 클립은 파일 경로에서 `g`로 표시되어 있습니다. 예를 들면, `v_ApplyEyeMakeup_g07_c04.avi`와 `v_ApplyEyeMakeup_g07_c06.avi` 이 있습니다. 이 둘은 같은 그룹입니다.
+
+검증 및 평가 데이터 분할을 할 때, [데이터 누출(data leakage)](https://www.kaggle.com/code/alexisbcook/data-leakage)을 방지하기 위해 동일한 그룹 / 장면의 영상 클립을 사용하지 않아야 합니다. 이 튜토리얼에서 사용하는 하위 집합은 이러한 정보를 고려하고 있습니다.
+
+그 다음으로, 데이터 세트에 존재하는 라벨을 추출합니다. 또한, 모델을 초기화할 때 도움이 될 딕셔너리(dictionary data type)를 생성합니다.
+
+* `label2id`: 클래스 이름을 정수에 매핑합니다.
+* `id2label`: 정수를 클래스 이름에 매핑합니다.
+
+```py
+>>> class_labels = sorted({str(path).split("/")[2] for path in all_video_file_paths})
+>>> label2id = {label: i for i, label in enumerate(class_labels)}
+>>> id2label = {i: label for label, i in label2id.items()}
+
+>>> print(f"Unique classes: {list(label2id.keys())}.")
+
+# Unique classes: ['ApplyEyeMakeup', 'ApplyLipstick', 'Archery', 'BabyCrawling', 'BalanceBeam', 'BandMarching', 'BaseballPitch', 'Basketball', 'BasketballDunk', 'BenchPress'].
+```
+
+이 데이터 세트에는 총 10개의 고유한 클래스가 있습니다. 각 클래스마다 30개의 영상이 훈련 세트에 있습니다
+
+## 미세 조정하기 위해 모델 가져오기 [[load-a-model-to-fine-tune]]
+
+사전 훈련된 체크포인트와 체크포인트에 연관된 이미지 프로세서를 사용하여 영상 분류 모델을 인스턴스화합니다. 모델의 인코더에는 미리 학습된 매개변수가 제공되며, 분류 헤드(데이터를 분류하는 마지막 레이어)는 무작위로 초기화됩니다. 데이터 세트의 전처리 파이프라인을 작성할 때는 이미지 프로세서가 유용합니다.
+
+```py
+>>> from transformers import VideoMAEImageProcessor, VideoMAEForVideoClassification
+
+>>> model_ckpt = "MCG-NJU/videomae-base"
+>>> image_processor = VideoMAEImageProcessor.from_pretrained(model_ckpt)
+>>> model = VideoMAEForVideoClassification.from_pretrained(
+... model_ckpt,
+... label2id=label2id,
+... id2label=id2label,
+... ignore_mismatched_sizes=True, # provide this in case you're planning to fine-tune an already fine-tuned checkpoint
+... )
+```
+
+모델을 가져오는 동안, 다음과 같은 경고를 마주칠 수 있습니다:
+
+```bash
+Some weights of the model checkpoint at MCG-NJU/videomae-base were not used when initializing VideoMAEForVideoClassification: [..., 'decoder.decoder_layers.1.attention.output.dense.bias', 'decoder.decoder_layers.2.attention.attention.key.weight']
+- This IS expected if you are initializing VideoMAEForVideoClassification from the checkpoint of a model trained on another task or with another architecture (e.g. initializing a BertForSequenceClassification model from a BertForPreTraining model).
+- This IS NOT expected if you are initializing VideoMAEForVideoClassification from the checkpoint of a model that you expect to be exactly identical (initializing a BertForSequenceClassification model from a BertForSequenceClassification model).
+Some weights of VideoMAEForVideoClassification were not initialized from the model checkpoint at MCG-NJU/videomae-base and are newly initialized: ['classifier.bias', 'classifier.weight']
+You should probably TRAIN this model on a down-stream task to be able to use it for predictions and inference.
+```
+
+
+위 경고는 우리가 일부 가중치(예: `classifier` 층의 가중치와 편향)를 버리고 새로운 `classifier` 층의 가중치와 편향을 무작위로 초기화하고 있다는 것을 알려줍니다. 이 경우에는 미리 학습된 가중치가 없는 새로운 헤드를 추가하고 있으므로, 라이브러리가 모델을 추론에 사용하기 전에 미세 조정하라고 경고를 보내는 것은 당연합니다. 그리고 이제 우리는 이 모델을 미세 조정할 예정입니다.
+
+**참고** 이 [체크포인트](https://huggingface.co/MCG-NJU/videomae-base-finetuned-kinetics)는 도메인이 많이 중첩된 유사한 다운스트림 작업에 대해 미세 조정하여 얻은 체크포인트이므로 이 작업에서 더 나은 성능을 보일 수 있습니다. `MCG-NJU/videomae-base-finetuned-kinetics` 데이터 세트를 미세 조정하여 얻은 [체크포인트](https://huggingface.co/sayakpaul/videomae-base-finetuned-kinetics-finetuned-ucf101-subset)도 있습니다.
+
+## 훈련을 위한 데이터 세트 준비하기[[prepare-the-datasets-for-training]]
+
+영상 전처리를 위해 [PyTorchVideo 라이브러리](https://pytorchvideo.org/)를 활용할 것입니다. 필요한 종속성을 가져오는 것으로 시작하세요.
+
+```py
+>>> import pytorchvideo.data
+
+>>> from pytorchvideo.transforms import (
+... ApplyTransformToKey,
+... Normalize,
+... RandomShortSideScale,
+... RemoveKey,
+... ShortSideScale,
+... UniformTemporalSubsample,
+... )
+
+>>> from torchvision.transforms import (
+... Compose,
+... Lambda,
+... RandomCrop,
+... RandomHorizontalFlip,
+... Resize,
+... )
+```
+
+학습 데이터 세트 변환에는 '균일한 시간 샘플링(uniform temporal subsampling)', '픽셀 정규화(pixel normalization)', '랜덤 잘라내기(random cropping)' 및 '랜덤 수평 뒤집기(random horizontal flipping)'의 조합을 사용합니다. 검증 및 평가 데이터 세트 변환에는 '랜덤 잘라내기'와 '랜덤 뒤집기'를 제외한 동일한 변환 체인을 유지합니다. 이러한 변환에 대해 자세히 알아보려면 [PyTorchVideo 공식 문서](https://pytorchvideo.org)를 확인하세요.
+
+사전 훈련된 모델과 관련된 이미지 프로세서를 사용하여 다음 정보를 얻을 수 있습니다:
+
+* 영상 프레임 픽셀을 정규화하는 데 사용되는 이미지 평균과 표준 편차
+* 영상 프레임이 조정될 공간 해상도
+
+
+먼저, 몇 가지 상수를 정의합니다.
+
+```py
+>>> mean = image_processor.image_mean
+>>> std = image_processor.image_std
+>>> if "shortest_edge" in image_processor.size:
+... height = width = image_processor.size["shortest_edge"]
+>>> else:
+... height = image_processor.size["height"]
+... width = image_processor.size["width"]
+>>> resize_to = (height, width)
+
+>>> num_frames_to_sample = model.config.num_frames
+>>> sample_rate = 4
+>>> fps = 30
+>>> clip_duration = num_frames_to_sample * sample_rate / fps
+```
+
+이제 데이터 세트에 특화된 전처리(transform)과 데이터 세트 자체를 정의합니다. 먼저 훈련 데이터 세트로 시작합니다:
+
+```py
+>>> train_transform = Compose(
+... [
+... ApplyTransformToKey(
+... key="video",
+... transform=Compose(
+... [
+... UniformTemporalSubsample(num_frames_to_sample),
+... Lambda(lambda x: x / 255.0),
+... Normalize(mean, std),
+... RandomShortSideScale(min_size=256, max_size=320),
+... RandomCrop(resize_to),
+... RandomHorizontalFlip(p=0.5),
+... ]
+... ),
+... ),
+... ]
+... )
+
+>>> train_dataset = pytorchvideo.data.Ucf101(
+... data_path=os.path.join(dataset_root_path, "train"),
+... clip_sampler=pytorchvideo.data.make_clip_sampler("random", clip_duration),
+... decode_audio=False,
+... transform=train_transform,
+... )
+```
+
+같은 방식의 작업 흐름을 검증과 평가 세트에도 적용할 수 있습니다.
+
+```py
+>>> val_transform = Compose(
+... [
+... ApplyTransformToKey(
+... key="video",
+... transform=Compose(
+... [
+... UniformTemporalSubsample(num_frames_to_sample),
+... Lambda(lambda x: x / 255.0),
+... Normalize(mean, std),
+... Resize(resize_to),
+... ]
+... ),
+... ),
+... ]
+... )
+
+>>> val_dataset = pytorchvideo.data.Ucf101(
+... data_path=os.path.join(dataset_root_path, "val"),
+... clip_sampler=pytorchvideo.data.make_clip_sampler("uniform", clip_duration),
+... decode_audio=False,
+... transform=val_transform,
+... )
+
+>>> test_dataset = pytorchvideo.data.Ucf101(
+... data_path=os.path.join(dataset_root_path, "test"),
+... clip_sampler=pytorchvideo.data.make_clip_sampler("uniform", clip_duration),
+... decode_audio=False,
+... transform=val_transform,
+... )
+```
+
+
+**참고**: 위의 데이터 세트의 파이프라인은 [공식 파이토치 예제](https://pytorchvideo.org/docs/tutorial_classification#dataset)에서 가져온 것입니다. 우리는 UCF-101 데이터셋에 맞게 [`pytorchvideo.data.Ucf101()`](https://pytorchvideo.readthedocs.io/en/latest/api/data/data.html#pytorchvideo.data.Ucf101) 함수를 사용하고 있습니다. 내부적으로 이 함수는 [`pytorchvideo.data.labeled_video_dataset.LabeledVideoDataset`](https://pytorchvideo.readthedocs.io/en/latest/api/data/data.html#pytorchvideo.data.LabeledVideoDataset) 객체를 반환합니다. `LabeledVideoDataset` 클래스는 PyTorchVideo 데이터셋에서 모든 영상 관련 작업의 기본 클래스입니다. 따라서 PyTorchVideo에서 미리 제공하지 않는 사용자 지정 데이터 세트를 사용하려면, 이 클래스를 적절하게 확장하면 됩니다. 더 자세한 사항이 알고 싶다면 `data` API [문서](https://pytorchvideo.readthedocs.io/en/latest/api/data/data.html) 를 참고하세요. 또한 위의 예시와 유사한 구조를 갖는 데이터 세트를 사용하고 있다면, `pytorchvideo.data.Ucf101()` 함수를 사용하는 데 문제가 없을 것입니다.
+
+데이터 세트에 영상의 개수를 알기 위해 `num_videos` 인수에 접근할 수 있습니다.
+
+```py
+>>> print(train_dataset.num_videos, val_dataset.num_videos, test_dataset.num_videos)
+# (300, 30, 75)
+```
+
+## 더 나은 디버깅을 위해 전처리 영상 시각화하기[[visualize-the-preprocessed-video-for-better-debugging]]
+
+```py
+>>> import imageio
+>>> import numpy as np
+>>> from IPython.display import Image
+
+>>> def unnormalize_img(img):
+... """Un-normalizes the image pixels."""
+... img = (img * std) + mean
+... img = (img * 255).astype("uint8")
+... return img.clip(0, 255)
+
+>>> def create_gif(video_tensor, filename="sample.gif"):
+... """Prepares a GIF from a video tensor.
+...
+... The video tensor is expected to have the following shape:
+... (num_frames, num_channels, height, width).
+... """
+... frames = []
+... for video_frame in video_tensor:
+... frame_unnormalized = unnormalize_img(video_frame.permute(1, 2, 0).numpy())
+... frames.append(frame_unnormalized)
+... kargs = {"duration": 0.25}
+... imageio.mimsave(filename, frames, "GIF", **kargs)
+... return filename
+
+>>> def display_gif(video_tensor, gif_name="sample.gif"):
+... """Prepares and displays a GIF from a video tensor."""
+... video_tensor = video_tensor.permute(1, 0, 2, 3)
+... gif_filename = create_gif(video_tensor, gif_name)
+... return Image(filename=gif_filename)
+
+>>> sample_video = next(iter(train_dataset))
+>>> video_tensor = sample_video["video"]
+>>> display_gif(video_tensor)
+```
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+더 나아가기 전에, 기존 Transformer 아키텍처에 대한 기본적인 지식을 숙지하는 것이 좋습니다. 인코더, 디코더 및 어텐션의 작동 방식을 알면 다양한 Transformer 모델이 어떻게 작동하는지 이해하는 데 도움이 됩니다. 시작 단계거나 복습이 필요한 경우, 더 많은 정보를 위해 [코스](https://huggingface.co/course/chapter1/4?fw=pt)를 확인하세요!
+
+
+
+## 음성 및 오디오[[speech-and-audio]]
+
+[Wav2Vec2](model_doc/wav2vec2)는 레이블이 지정되지 않은 음성 데이터에 대해 사전훈련된 모델로, 오디오 분류 및 자동 음성 인식을 위해 레이블이 지정된 데이터로 미세 조정합니다.
+
+
+
+
+
+세 번째 방법은 Transformer와 합성곱(예를 들어, [Convolutional Vision Transformer](model_doc/cvt) 또는 [LeViT](model_doc/levit))을 결합하는 것입니다. 우리는 살펴볼 두 가지 방법만 결합하기 때문에 여기서 이 방법을 다루지 않습니다.
+
+
+
+ViT와 ConvNeXT는 일반적으로 이미지 분류에서 사용되지만, 물체 감지, 분할, 깊이 추정과 같은 다른 비전 작업에는 각각 DETR, Mask2Former, GLPN이 더 적합하므로 이러한 모델을 살펴보겠습니다.
+
+### 이미지 분류[[image-classification]]
+
+ViT와 ConvNeXT 모두 이미지 분류에 사용될 수 있지만, ViT는 어텐션 메커니즘을, ConvNeXT는 합성곱을 사용하는 것이 주된 차이입니다.
+
+#### Transformer[[transformer]]
+
+[ViT](model_doc/vit)은 합성곱을 전적으로 순수 Transformer 아키텍처로 대체합니다. 기존 Transformer에 익숙하다면, ViT를 이해하는 방법의 대부분을 이미 파악했다고 볼 수 있습니다.
+
+
+
+
+
+이 섹션에서는 합성곱에 대해 간략하게 설명합니다. 그러나 이미지의 모양과 크기가 어떻게 변화하는지에 대한 사전 이해가 있다면 도움이 될 것입니다. 합성곱에 익숙하지 않은 경우, fastai book의 [합성곱 신경망 챕터](https://github.com/fastai/fastbook/blob/master/13_convolutions.ipynb)를 확인하세요!
+
+
+
+[ConvNeXT](model_doc/convnext)는 성능을 높이기 위해 새로운 현대 네트워크 설계를 적용한 CNN 구조입니다. 그러나 합성곱은 여전히 모델의 핵심입니다. 높은 수준의 관점에서 볼 때, [합성곱](glossary#convolution)은 작은 행렬(*커널*)에 이미지 픽셀의 작은 윈도우를 곱하는 연산입니다. 이는 특정 텍스쳐(texture)이나 선의 곡률과 같은 일부 특징을 계산합니다. 그러고 다음 픽셀 윈도우로 넘어가는데, 여기서 합성곱이 이동하는 거리를 *보폭(stride)*이라고 합니다.
+
+
+
+
패딩이나 보폭이 없는 기본 합성곱, 딥러닝을 위한 합성곱 연산 가이드
+
+이 출력을 다른 합성곱 레이어에 전달할 수 있으며, 각 연속적인 레이어를 통해 네트워크는 핫도그나 로켓과 같이 더 복잡하고 추상적인 것을 학습합니다. 합성곱 레이어 사이에 풀링 레이어를 추가하여 차원을 줄이고 특징의 위치 변화에 대해 모델을 더 견고하게 만드는 것이 일반적입니다.
+
+
+
+
+
+
+
+
+
+
+
+💡 사전훈련된 BERT를 다양한 작업에 사용하는 것이 얼마나 쉬운지 주목하세요. 사전훈련된 모델에 특정 헤드를 추가하기만 하면 은닉 상태를 원하는 출력으로 조작할 수 있습니다!
+
+
+
+### 텍스트 생성[[text-generation]]
+
+[GPT-2](model_doc/gpt2)는 대량의 텍스트에 대해 사전훈련된 디코딩 전용 모델입니다. 프롬프트를 주어지면 설득력 있는 (항상 사실은 아니지만!) 텍스트를 생성하고 명시적으로 훈련되지 않았음에도 불구하고 질의응답과 같은 다른 NLP 작업을 완수할 수 있습니다.
+
+
+
+
+
+텍스트 생성에 대한 자세한 내용은 [텍스트 생성 전략](generation_strategies) 가이드를 확인하세요!
+
+
+
+### 요약[[summarization]]
+
+[BART](model_doc/bart) 및 [T5](model_doc/t5)와 같은 인코더-디코더 모델은 요약 작업의 시퀀스-투-시퀀스 패턴을 위해 설계되었습니다. 이 섹션에서 BART의 작동 방법을 설명한 다음, 마지막에 T5를 미세 조정해볼 수 있습니다.
+
+
+
+
+
+텍스트 생성에 대한 자세한 내용은 [텍스트 생성 전략](generation_strategies) 가이드를 확인하세요!
+
+
+
+### 번역[[translation]]
+
+번역은 시퀀스-투-시퀀스 작업의 또 다른 예로, [BART](model_doc/bart) 또는 [T5](model_doc/t5)와 같은 인코더-디코더 모델을 사용할 수 있습니다. 이 섹션에서 BART의 작동 방법을 설명한 다음, 마지막에 T5를 미세 조정해볼 수 있습니다.
+
+BART는 원천 언어를 타겟 언어로 디코딩할 수 있는 입력에 매핑하기 위해 무작위로 초기화된 별도의 인코더를 추가하여 번역에 적용합니다. 이 새로운 인코더의 임베딩은 원본 단어 임베딩 대신 사전훈련된 인코더로 전달됩니다. 원천 인코더는 모델 출력의 교차 엔트로피 손실로부터 원천 인코더, 위치 임베딩, 입력 임베딩을 갱신하여 훈련됩니다. 첫 번째 단계에서는 모델 파라미터가 고정되고, 두 번째 단계에서는 모든 모델 파라미터가 함께 훈련됩니다.
+
+BART는 이후 번역을 위해 다양한 언어로 사전훈련된 다국어 버전의 mBART로 확장되었습니다.
+
+번역에 직접 도전할 준비가 되셨나요? 완전한 [번역 가이드](tasks/summarization)를 확인하여 T5를 미세 조정하고 추론에 사용하는 방법을 학습하세요!
+
+
+
+텍스트 생성에 대한 자세한 내용은 [텍스트 생성 전략](generation_strategies) 가이드를 확인하세요!
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/testing.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/testing.md
new file mode 100644
index 0000000000000000000000000000000000000000..fd3f548eeb812910fda5c0040ceb8cb6710538e0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/testing.md
@@ -0,0 +1,1278 @@
+
+
+# 테스트[[testing]]
+
+
+먼저 🤗 Transformers 모델이 어떻게 테스트되는지 살펴보고, 새로운 테스트를 작성 및 기존 테스트를 개선하는 방법을 알아봅시다.
+
+이 저장소에는 2개의 테스트 스위트가 있습니다:
+
+1. `tests` - 일반 API에 대한 테스트
+2. `examples` - API의 일부가 아닌 다양한 응용 프로그램에 대한 테스트
+
+## Transformers 테스트 방법[[how-transformers-are-tested]]
+
+1. PR이 제출되면 9개의 CircleCi 작업으로 테스트가 진행됩니다. 해당 PR에 대해 새로운 커밋이 생성될 때마다 테스트는 다시 진행됩니다. 이 작업들은
+ 이 [config 파일](https://github.com/huggingface/transformers/tree/main/.circleci/config.yml)에 정의되어 있으므로 필요하다면
+ 사용자의 로컬 환경에서 동일하게 재현해 볼 수 있습니다.
+
+ 이 CI 작업은 `@slow` 테스트를 실행하지 않습니다.
+
+2. [github actions](https://github.com/huggingface/transformers/actions)에 의해 실행되는 작업은 3개입니다:
+
+ - [torch hub integration](https://github.com/huggingface/transformers/tree/main/.github/workflows/github-torch-hub.yml):
+ torch hub integration이 작동하는지 확인합니다.
+
+ - [self-hosted (push)](https://github.com/huggingface/transformers/tree/main/.github/workflows/self-push.yml): `main` 브랜치에서 커밋이 업데이트된 경우에만 GPU를 이용한 빠른 테스트를 실행합니다.
+ 이는 `src`, `tests`, `.github` 폴더 중 하나에 코드가 업데이트된 경우에만 실행됩니다.
+ (model card, notebook, 기타 등등을 추가한 경우 실행되지 않도록 하기 위해서입니다)
+
+ - [self-hosted runner](https://github.com/huggingface/transformers/tree/main/.github/workflows/self-scheduled.yml): `tests` 및 `examples`에서
+ GPU를 이용한 일반 테스트, 느린 테스트를 실행합니다.
+
+
+```bash
+RUN_SLOW=1 pytest tests/
+RUN_SLOW=1 pytest examples/
+```
+
+ 결과는 [여기](https://github.com/huggingface/transformers/actions)에서 확인할 수 있습니다.
+
+
+## 테스트 실행[[running-tests]]
+
+
+
+
+
+### 실행할 테스트 선택[[choosing-which-tests-to-run]]
+
+이 문서는 테스트를 실행하는 다양한 방법에 대해 자세히 설명합니다.
+모든 내용을 읽은 후에도, 더 자세한 내용이 필요하다면 [여기](https://docs.pytest.org/en/latest/usage.html)에서 확인할 수 있습니다.
+
+다음은 가장 유용한 테스트 실행 방법 몇 가지입니다.
+
+모두 실행:
+
+```console
+pytest
+```
+
+또는:
+
+```bash
+make test
+```
+
+후자는 다음과 같이 정의됩니다:
+
+```bash
+python -m pytest -n auto --dist=loadfile -s -v ./tests/
+```
+
+위의 명령어는 pytest에게 아래의 내용을 전달합니다:
+
+- 사용 가능한 CPU 코어 수만큼 테스트 프로세스를 실행합니다. (RAM이 충분하지 않다면, 테스트 프로세스 수가 너무 많을 수 있습니다!)
+- 동일한 파일의 모든 테스트는 동일한 테스트 프로세스에서 실행되어야 합니다.
+- 출력을 캡처하지 않습니다.
+- 자세한 모드로 실행합니다.
+
+
+
+### 모든 테스트 목록 가져오기[[getting-the-list-of-all-tests]]
+
+테스트 스위트의 모든 테스트:
+
+```bash
+pytest --collect-only -q
+```
+
+지정된 테스트 파일의 모든 테스트:
+
+```bash
+pytest tests/test_optimization.py --collect-only -q
+```
+
+### 특정 테스트 모듈 실행[[run-a-specific-test-module]]
+
+개별 테스트 모듈 실행하기:
+
+```bash
+pytest tests/utils/test_logging.py
+```
+
+### 특정 테스트 실행[[run-specific-tests]]
+
+대부분의 테스트 내부에서는 unittest가 사용됩니다. 따라서 특정 하위 테스트를 실행하려면 해당 테스트를 포함하는 unittest 클래스의 이름을 알아야 합니다.
+예를 들어 다음과 같을 수 있습니다:
+
+```bash
+pytest tests/test_optimization.py::OptimizationTest::test_adam_w
+```
+
+위의 명령어의 의미는 다음과 같습니다:
+
+- `tests/test_optimization.py` - 테스트가 있는 파일
+- `OptimizationTest` - 클래스의 이름
+- `test_adam_w` - 특정 테스트 함수의 이름
+
+파일에 여러 클래스가 포함된 경우, 특정 클래스의 테스트만 실행할 수도 있습니다. 예를 들어 다음과 같습니다:
+
+```bash
+pytest tests/test_optimization.py::OptimizationTest
+```
+
+이 명령어는 해당 클래스 내부의 모든 테스트를 실행합니다.
+
+앞에서 언급한 것처럼 `OptimizationTest` 클래스에 포함된 테스트를 확인할 수 있습니다.
+
+```bash
+pytest tests/test_optimization.py::OptimizationTest --collect-only -q
+```
+
+키워드 표현식을 사용하여 테스트를 실행할 수도 있습니다.
+
+`adam`이라는 이름을 포함하는 테스트만 실행하려면 다음과 같습니다:
+
+```bash
+pytest -k adam tests/test_optimization.py
+```
+
+논리 연산자 `and`와 `or`를 사용하여 모든 키워드가 일치해야 하는지 또는 어느 하나가 일치해야 하는지를 나타낼 수 있습니다.
+`not`은 부정할 때 사용할 수 있습니다.
+
+`adam`이라는 이름을 포함하지 않는 모든 테스트를 실행하려면 다음과 같습니다:
+
+```bash
+pytest -k "not adam" tests/test_optimization.py
+```
+
+두 가지 패턴을 하나로 결합할 수도 있습니다:
+
+```bash
+pytest -k "ada and not adam" tests/test_optimization.py
+```
+
+예를 들어 `test_adafactor`와 `test_adam_w`를 모두 실행하려면 다음을 사용할 수 있습니다:
+
+```bash
+pytest -k "test_adam_w or test_adam_w" tests/test_optimization.py
+```
+
+여기서 `or`를 사용하는 것에 유의하세요. 두 키워드 중 하나가 일치하도록 하기 위한 목적으로 사용하기 때문입니다.
+
+두 패턴이 모두 포함되어야 하는 테스트만 실행하려면, `and`를 사용해야 합니다:
+
+```bash
+pytest -k "test and ada" tests/test_optimization.py
+```
+
+### `accelerate` 테스트 실행[[run-`accelerate`-tests]]
+
+모델에서 `accelerate` 테스트를 실행해야 할 때가 있습니다. 이를 위해서는 명령어에 `-m accelerate_tests`를 추가하면 됩니다.
+예를 들어, `OPT`에서 이러한 테스트를 실행하려면 다음과 같습니다:
+```bash
+RUN_SLOW=1 pytest -m accelerate_tests tests/models/opt/test_modeling_opt.py
+```
+
+### 문서 테스트 실행[[run-documentation-tests]]
+
+예시 문서가 올바른지 테스트하려면 `doctests`가 통과하는지 확인해야 합니다.
+예를 들어, [`WhisperModel.forward`'s docstring](https://github.com/huggingface/transformers/blob/main/src/transformers/models/whisper/modeling_whisper.py#L1017-L1035)를 사용해 봅시다:
+
+```python
+r"""
+Returns:
+
+Example:
+ ```python
+ >>> import torch
+ >>> from transformers import WhisperModel, WhisperFeatureExtractor
+ >>> from datasets import load_dataset
+
+ >>> model = WhisperModel.from_pretrained("openai/whisper-base")
+ >>> feature_extractor = WhisperFeatureExtractor.from_pretrained("openai/whisper-base")
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> inputs = feature_extractor(ds[0]["audio"]["array"], return_tensors="pt")
+ >>> input_features = inputs.input_features
+ >>> decoder_input_ids = torch.tensor([[1, 1]]) * model.config.decoder_start_token_id
+ >>> last_hidden_state = model(input_features, decoder_input_ids=decoder_input_ids).last_hidden_state
+ >>> list(last_hidden_state.shape)
+ [1, 2, 512]
+ ```"""
+
+```
+
+원하는 파일의 모든 docstring 예제를 자동으로 테스트하려면 다음 명령을 실행하면 됩니다:
+```bash
+pytest --doctest-modules
+```
+파일의 확장자가 markdown인 경우 `--doctest-glob="*.md"` 인수를 추가해야 합니다.
+
+### 수정된 테스트만 실행[[run-only-modified-tests]]
+
+수정된 파일 또는 현재 브랜치 (Git 기준)와 관련된 테스트를 실행하려면 [pytest-picked](https://github.com/anapaulagomes/pytest-picked)을 사용할 수 있습니다.
+이는 변경한 내용이 테스트에 영향을 주지 않았는지 빠르게 확인할 수 있는 좋은 방법입니다.
+
+```bash
+pip install pytest-picked
+```
+
+```bash
+pytest --picked
+```
+
+수정되었지만, 아직 커밋되지 않은 모든 파일 및 폴더에서 테스트가 실행됩니다.
+
+### 소스 수정 시 실패한 테스트 자동 재실행[[automatically-rerun-failed-tests-on-source-modification]]
+
+[pytest-xdist](https://github.com/pytest-dev/pytest-xdist)는 모든 실패한 테스트를 감지하고,
+파일을 수정한 후에 파일을 계속 재실행하여 테스트가 성공할 때까지 기다리는 매우 유용한 기능을 제공합니다.
+따라서 수정한 내용을 확인한 후 pytest를 다시 시작할 필요가 없습니다.
+모든 테스트가 통과될 때까지 이 과정을 반복한 후 다시 전체 실행이 이루어집니다.
+
+```bash
+pip install pytest-xdist
+```
+
+재귀적 모드의 사용: `pytest -f` 또는 `pytest --looponfail`
+
+파일의 변경 사항은 `looponfailroots` 루트 디렉터리와 해당 내용을 (재귀적으로) 확인하여 감지됩니다.
+이 값의 기본값이 작동하지 않는 경우,
+`setup.cfg`의 설정 옵션을 변경하여 프로젝트에서 변경할 수 있습니다:
+
+```ini
+[tool:pytest]
+looponfailroots = transformers tests
+```
+
+또는 `pytest.ini`/`tox.ini`` 파일:
+
+```ini
+[pytest]
+looponfailroots = transformers tests
+```
+
+이렇게 하면 ini-file의 디렉터리를 기준으로 상대적으로 지정된 각 디렉터리에서 파일 변경 사항만 찾게 됩니다.
+
+
+이 기능을 대체할 수 있는 구현 방법인 [pytest-watch](https://github.com/joeyespo/pytest-watch)도 있습니다.
+
+
+### 특정 테스트 모듈 건너뛰기[[skip-a-test-module]]
+
+모든 테스트 모듈을 실행하되 특정 모듈을 제외하려면, 실행할 테스트 목록을 명시적으로 지정할 수 있습니다.
+예를 들어, `test_modeling_*.py` 테스트를 제외한 모든 테스트를 실행하려면 다음을 사용할 수 있습니다:
+
+```bash
+pytest *ls -1 tests/*py | grep -v test_modeling*
+```
+
+### 상태 초기화[[clearing state]]
+
+CI 빌드 및 (속도에 대한) 격리가 중요한 경우, 캐시를 지워야 합니다:
+
+```bash
+pytest --cache-clear tests
+```
+
+### 테스트를 병렬로 실행[[running-tests-in-parallel]]
+
+이전에 언급한 것처럼 `make test`는 테스트를 병렬로 실행하기 위해
+`pytest-xdist` 플러그인(`-n X` 인수, 예를 들어 `-n 2`를 사용하여 2개의 병렬 작업 실행)을 통해 실행됩니다.
+
+`pytest-xdist`의 `--dist=` 옵션을 사용하여 테스트를 어떻게 그룹화할지 제어할 수 있습니다.
+`--dist=loadfile`은 하나의 파일에 있는 테스트를 동일한 프로세스로 그룹화합니다.
+
+실행된 테스트의 순서가 다르고 예측할 수 없기 때문에, `pytest-xdist`로 테스트 스위트를 실행하면 실패가 발생할 수 있습니다 (검출되지 않은 결합된 테스트가 있는 경우).
+이 경우 [pytest-replay](https://github.com/ESSS/pytest-replay)를 사용하면 동일한 순서로 테스트를 다시 실행해서
+실패하는 시퀀스를 최소화하는 데에 도움이 됩니다.
+
+### 테스트 순서와 반복[[test-order-and-repetition]]
+
+잠재적인 종속성 및 상태 관련 버그(tear down)를 감지하기 위해
+테스트를 여러 번, 연속으로, 무작위로 또는 세트로 반복하는 것이 좋습니다.
+그리고 직접적인 여러 번의 반복은 DL의 무작위성에 의해 발견되는 일부 문제를 감지하는 데에도 유용합니다.
+
+
+#### 테스트를 반복[[repeat-tests]]
+
+- [pytest-flakefinder](https://github.com/dropbox/pytest-flakefinder):
+
+```bash
+pip install pytest-flakefinder
+```
+
+모든 테스트를 여러 번 실행합니다(기본값은 50번):
+
+```bash
+pytest --flake-finder --flake-runs=5 tests/test_failing_test.py
+```
+
+
+
+이 플러그인은 `pytest-xdist`의 `-n` 플래그와 함께 작동하지 않습니다.
+
+
+
+
+
+`pytest-repeat`라는 또 다른 플러그인도 있지만 `unittest`와 함께 작동하지 않습니다.
+
+
+
+#### 테스트를 임의의 순서로 실행[[run-tests-in-a-random-order]]
+
+```bash
+pip install pytest-random-order
+```
+
+중요: `pytest-random-order`가 설치되면 테스트가 자동으로 임의의 순서로 섞입니다.
+구성 변경이나 커맨드 라인 옵션이 필요하지 않습니다.
+
+앞서 설명한 것처럼 이를 통해 한 테스트의 상태가 다른 테스트의 상태에 영향을 미치는 결합된 테스트를 감지할 수 있습니다.
+`pytest-random-order`가 설치되면 해당 세션에서 사용된 랜덤 시드가 출력되며 예를 들어 다음과 같습니다:
+
+```bash
+pytest tests
+[...]
+Using --random-order-bucket=module
+Using --random-order-seed=573663
+```
+
+따라서 특정 시퀀스가 실패하는 경우에는 정확한 시드를 추가하여 재현할 수 있습니다. 예를 들어 다음과 같습니다:
+
+```bash
+pytest --random-order-seed=573663
+[...]
+Using --random-order-bucket=module
+Using --random-order-seed=573663
+```
+
+정확히 동일한 테스트 목록(또는 목록이 없음)을 사용하는 경우에만 정확한 순서를 재현합니다.
+목록을 수동으로 좁히기 시작하면 더 이상 시드에 의존할 수 없고 실패했던 정확한 순서로 수동으로 목록을 나열해야합니다. 그리고 `--random-order-bucket=none`을 사용하여 pytest에게 순서를 임의로 설정하지 않도록 알려야 합니다.
+예를 들어 다음과 같습니다:
+
+```bash
+pytest --random-order-bucket=none tests/test_a.py tests/test_c.py tests/test_b.py
+```
+
+모든 테스트에 대해 섞기를 비활성화하려면 다음과 같습니다:
+
+```bash
+pytest --random-order-bucket=none
+```
+
+기본적으로 `--random-order-bucket=module`이 내재되어 있으므로, 모듈 수준에서 파일을 섞습니다.
+또한 `class`, `package`, `global` 및 `none` 수준에서도 섞을 수 있습니다.
+자세한 내용은 해당 [문서](https://github.com/jbasko/pytest-random-order)를 참조하세요.
+
+또 다른 무작위화의 대안은 [`pytest-randomly`](https://github.com/pytest-dev/pytest-randomly)입니다.
+이 모듈은 매우 유사한 기능/인터페이스를 가지고 있지만, `pytest-random-order`에 있는 버킷 모드를 사용할 수는 없습니다.
+설치 후에는 자동으로 적용되는 문제도 동일하게 가집니다.
+
+### 외관과 느낌을 변경[[look-and-feel-variations]
+
+#### pytest-sugar 사용[[pytest-sugar]]
+
+[pytest-sugar](https://github.com/Frozenball/pytest-sugar)는 테스트가 보여지는 형태를 개선하고,
+진행 상황 바를 추가하며, 실패한 테스트와 검증을 즉시 표시하는 플러그인입니다. 설치하면 자동으로 활성화됩니다.
+
+```bash
+pip install pytest-sugar
+```
+
+pytest-sugar 없이 테스트를 실행하려면 다음과 같습니다:
+
+```bash
+pytest -p no:sugar
+```
+
+또는 제거하세요.
+
+
+
+#### 각 하위 테스트 이름과 진행 상황 보고[[report-each-sub-test-name-and-its-progress]]
+
+`pytest`를 통해 단일 또는 그룹의 테스트를 실행하는 경우(`pip install pytest-pspec` 이후):
+
+```bash
+pytest --pspec tests/test_optimization.py
+```
+
+#### 실패한 테스트 즉시 표시[[instantly-shows-failed-tests]]
+
+[pytest-instafail](https://github.com/pytest-dev/pytest-instafail)은 테스트 세션의 끝까지 기다리지 않고
+실패 및 오류를 즉시 표시합니다.
+
+```bash
+pip install pytest-instafail
+```
+
+```bash
+pytest --instafail
+```
+
+### GPU 사용 여부[[to-GPU-or-not-to-GPU]]
+
+GPU가 활성화된 환경에서, CPU 전용 모드로 테스트하려면 `CUDA_VISIBLE_DEVICES=""`를 추가합니다:
+
+```bash
+CUDA_VISIBLE_DEVICES="" pytest tests/utils/test_logging.py
+```
+
+또는 다중 GPU가 있는 경우 `pytest`에서 사용할 GPU를 지정할 수도 있습니다.
+예를 들어, GPU `0` 및 `1`이 있는 경우 다음을 실행할 수 있습니다:
+
+```bash
+CUDA_VISIBLE_DEVICES="1" pytest tests/utils/test_logging.py
+```
+
+이렇게 하면 다른 GPU에서 다른 작업을 실행하려는 경우 유용합니다.
+
+일부 테스트는 반드시 CPU 전용으로 실행해야 하며, 일부는 CPU 또는 GPU 또는 TPU에서 실행해야 하고, 일부는 여러 GPU에서 실행해야 합니다.
+다음 스킵 데코레이터는 테스트의 요구 사항을 CPU/GPU/TPU별로 설정하는 데 사용됩니다:
+
+- `require_torch` - 이 테스트는 torch에서만 실행됩니다.
+- `require_torch_gpu` - `require_torch`에 추가로 적어도 1개의 GPU가 필요합니다.
+- `require_torch_multi_gpu` - `require_torch`에 추가로 적어도 2개의 GPU가 필요합니다.
+- `require_torch_non_multi_gpu` - `require_torch`에 추가로 0개 또는 1개의 GPU가 필요합니다.
+- `require_torch_up_to_2_gpus` - `require_torch`에 추가로 0개, 1개 또는 2개의 GPU가 필요합니다.
+- `require_torch_xla` - `require_torch`에 추가로 적어도 1개의 TPU가 필요합니다.
+
+GPU 요구 사항을 표로 정리하면 아래와 같습니디ㅏ:
+
+
+| n gpus | decorator |
+|--------+--------------------------------|
+| `>= 0` | `@require_torch` |
+| `>= 1` | `@require_torch_gpu` |
+| `>= 2` | `@require_torch_multi_gpu` |
+| `< 2` | `@require_torch_non_multi_gpu` |
+| `< 3` | `@require_torch_up_to_2_gpus` |
+
+
+예를 들어, 2개 이상의 GPU가 있고 pytorch가 설치되어 있을 때에만 실행되어야 하는 테스트는 다음과 같습니다:
+
+```python no-style
+@require_torch_multi_gpu
+def test_example_with_multi_gpu():
+```
+
+`tensorflow`가 필요한 경우 `require_tf` 데코레이터를 사용합니다. 예를 들어 다음과 같습니다:
+
+```python no-style
+@require_tf
+def test_tf_thing_with_tensorflow():
+```
+
+이러한 데코레이터는 중첩될 수 있습니다.
+예를 들어, 느린 테스트로 진행되고 pytorch에서 적어도 하나의 GPU가 필요한 경우 다음과 같이 설정할 수 있습니다:
+
+```python no-style
+@require_torch_gpu
+@slow
+def test_example_slow_on_gpu():
+```
+
+`@parametrized`와 같은 일부 데코레이터는 테스트 이름을 다시 작성하기 때문에 `@require_*` 스킵 데코레이터는 올바르게 작동하려면 항상 맨 마지막에 나열되어야 합니다.
+다음은 올바른 사용 예입니다:
+
+```python no-style
+@parameterized.expand(...)
+@require_torch_multi_gpu
+def test_integration_foo():
+```
+
+`@pytest.mark.parametrize`에는 이러한 순서 문제는 없으므로 처음 혹은 마지막에 위치시킬 수 있고 이러한 경우에도 잘 작동할 것입니다.
+하지만 unittest가 아닌 경우에만 작동합니다.
+
+테스트 내부에서 다음을 사용할 수 있습니다:
+
+- 사용 가능한 GPU 수:
+
+```python
+from transformers.testing_utils import get_gpu_count
+
+n_gpu = get_gpu_count() #torch와 tf와 함께 작동
+```
+
+### 분산 훈련[[distributed-training]]
+
+`pytest`는 분산 훈련을 직접적으로 다루지 못합니다.
+이를 시도하면 하위 프로세스가 올바른 작업을 수행하지 않고 `pytest`라고 생각하기에 테스트 스위트를 반복해서 실행하게 됩니다.
+그러나 일반 프로세스를 생성한 다음 여러 워커를 생성하고 IO 파이프를 관리하도록 하면 동작합니다.
+
+다음은 사용 가능한 테스트입니다:
+
+- [test_trainer_distributed.py](https://github.com/huggingface/transformers/tree/main/tests/trainer/test_trainer_distributed.py)
+- [test_deepspeed.py](https://github.com/huggingface/transformers/tree/main/tests/deepspeed/test_deepspeed.py)
+
+실행 지점으로 바로 이동하려면, 해당 테스트에서 `execute_subprocess_async` 호출을 검색하세요.
+
+이러한 테스트를 실행하려면 적어도 2개의 GPU가 필요합니다.
+
+```bash
+CUDA_VISIBLE_DEVICES=0,1 RUN_SLOW=1 pytest -sv tests/test_trainer_distributed.py
+```
+
+### 출력 캡처[[output-capture]]
+
+테스트 실행 중 `stdout` 및 `stderr`로 전송된 모든 출력이 캡처됩니다.
+테스트나 설정 메소드가 실패하면 캡처된 출력은 일반적으로 실패 추적 정보와 함께 표시됩니다.
+
+출력 캡처를 비활성화하고 `stdout` 및 `stderr`를 정상적으로 받으려면 `-s` 또는 `--capture=no`를 사용하세요:
+
+```bash
+pytest -s tests/utils/test_logging.py
+```
+
+테스트 결과를 JUnit 형식의 출력으로 보내려면 다음을 사용하세요:
+
+```bash
+py.test tests --junitxml=result.xml
+```
+
+### 색상 조절[[color-control]]
+
+색상이 없게 하려면 다음과 같이 설정하세요(예를 들어 흰색 배경에 노란색 글씨는 가독성이 좋지 않습니다):
+
+```bash
+pytest --color=no tests/utils/test_logging.py
+```
+
+### online pastebin service에 테스트 보고서 전송[[sending test report to online pastebin service]]
+
+각 테스트 실패에 대한 URL을 만듭니다:
+
+```bash
+pytest --pastebin=failed tests/utils/test_logging.py
+```
+
+이렇게 하면 각 실패에 대한 URL을 제공하는 remote Paste service에 테스트 실행 정보를 제출합니다.
+일반적인 테스트를 선택할 수도 있고 혹은 특정 실패만 보내려면 `-x`와 같이 추가할 수도 있습니다.
+
+전체 테스트 세션 로그에 대한 URL을 생성합니다:
+
+```bash
+pytest --pastebin=all tests/utils/test_logging.py
+```
+
+## 테스트 작성[[writing-tests]]
+
+🤗 transformers 테스트는 대부분 `unittest`를 기반으로 하지만,
+`pytest`에서 실행되므로 대부분의 경우 두 시스템의 기능을 사용할 수 있습니다.
+
+지원되는 기능에 대해 [여기](https://docs.pytest.org/en/stable/unittest.html)에서 확인할 수 있지만,
+기억해야 할 중요한 점은 대부분의 `pytest` fixture가 작동하지 않는다는 것입니다.
+파라미터화도 작동하지 않지만, 우리는 비슷한 방식으로 작동하는 `parameterized` 모듈을 사용합니다.
+
+
+### 매개변수화[[parametrization]]
+
+동일한 테스트를 다른 인수로 여러 번 실행해야 하는 경우가 종종 있습니다.
+테스트 내에서 이 작업을 수행할 수 있지만, 그렇게 하면 하나의 인수 세트에 대해 테스트를 실행할 수 없습니다.
+
+```python
+# test_this1.py
+import unittest
+from parameterized import parameterized
+
+
+class TestMathUnitTest(unittest.TestCase):
+ @parameterized.expand(
+ [
+ ("negative", -1.5, -2.0),
+ ("integer", 1, 1.0),
+ ("large fraction", 1.6, 1),
+ ]
+ )
+ def test_floor(self, name, input, expected):
+ assert_equal(math.floor(input), expected)
+```
+
+이제 기본적으로 이 테스트는 `test_floor`의 마지막 3개 인수가
+매개변수 목록의 해당 인수에 할당되는 것으로 3번 실행될 것입니다.
+
+그리고 `negative` 및 `integer` 매개변수 집합만 실행하려면 다음과 같이 실행할 수 있습니다:
+
+```bash
+pytest -k "negative and integer" tests/test_mytest.py
+```
+
+또는 `negative` 하위 테스트를 제외한 모든 서브 테스트를 다음과 같이 실행할 수 있습니다:
+
+```bash
+pytest -k "not negative" tests/test_mytest.py
+```
+
+앞에서 언급한 `-k` 필터를 사용하는 것 외에도,
+각 서브 테스트의 정확한 이름을 확인한 후에 일부 혹은 전체 서브 테스트를 실행할 수 있습니다.
+
+```bash
+pytest test_this1.py --collect-only -q
+```
+
+그리고 다음의 내용을 확인할 수 있을 것입니다:
+
+```bash
+test_this1.py::TestMathUnitTest::test_floor_0_negative
+test_this1.py::TestMathUnitTest::test_floor_1_integer
+test_this1.py::TestMathUnitTest::test_floor_2_large_fraction
+```
+
+2개의 특정한 서브 테스트만 실행할 수도 있습니다:
+
+```bash
+pytest test_this1.py::TestMathUnitTest::test_floor_0_negative test_this1.py::TestMathUnitTest::test_floor_1_integer
+```
+
+`transformers`의 개발자 종속성에 이미 있는 [parameterized](https://pypi.org/project/parameterized/) 모듈은
+`unittests`와 `pytest` 테스트 모두에서 작동합니다.
+
+그러나 테스트가 `unittest`가 아닌 경우 `pytest.mark.parametrize`를 사용할 수 있습니다(이미 있는 일부 테스트에서 사용되는 경우도 있습니다.
+주로 `examples` 하위에 있습니다).
+
+다음은 `pytest`의 `parametrize` 마커를 사용한 동일한 예입니다:
+
+```python
+# test_this2.py
+import pytest
+
+
+@pytest.mark.parametrize(
+ "name, input, expected",
+ [
+ ("negative", -1.5, -2.0),
+ ("integer", 1, 1.0),
+ ("large fraction", 1.6, 1),
+ ],
+)
+def test_floor(name, input, expected):
+ assert_equal(math.floor(input), expected)
+```
+
+`parameterized`와 마찬가지로 `pytest.mark.parametrize`를 사용하면
+`-k` 필터가 작동하지 않는 경우에도 실행할 서브 테스트를 정확하게 지정할 수 있습니다.
+단, 이 매개변수화 함수는 서브 테스트의 이름 집합을 약간 다르게 생성합니다. 다음과 같은 모습입니다:
+
+```bash
+pytest test_this2.py --collect-only -q
+```
+
+그리고 다음의 내용을 확인할 수 있을 것입니다:
+
+```bash
+test_this2.py::test_floor[integer-1-1.0]
+test_this2.py::test_floor[negative--1.5--2.0]
+test_this2.py::test_floor[large fraction-1.6-1]
+```
+
+특정한 테스트에 대해서만 실행할 수도 있습니다:
+
+```bash
+pytest test_this2.py::test_floor[negative--1.5--2.0] test_this2.py::test_floor[integer-1-1.0]
+```
+
+이전의 예시와 같이 실행할 수 있습니다.
+
+
+
+### 파일 및 디렉터리[[files-and-directories]]
+
+테스트에서 종종 현재 테스트 파일과 관련된 상대적인 위치를 알아야 하는 경우가 있습니다.
+테스트가 여러 디렉터리에서 호출되거나 깊이가 다른 하위 디렉터리에 있을 수 있기 때문에 그 위치를 아는 것은 간단하지 않습니다.
+`transformers.test_utils.TestCasePlus`라는 헬퍼 클래스는 모든 기본 경로를 처리하고 간단한 액세서를 제공하여 이 문제를 해결합니다:
+
+
+- `pathlib` 객체(완전히 정해진 경로)
+
+ - `test_file_path` - 현재 테스트 파일 경로 (예: `__file__`)
+ - test_file_dir` - 현재 테스트 파일이 포함된 디렉터리
+ - tests_dir` - `tests` 테스트 스위트의 디렉터리
+ - examples_dir` - `examples` 테스트 스위트의 디렉터리
+ - repo_root_dir` - 저장소 디렉터리
+ - src_dir` - `src`의 디렉터리(예: `transformers` 하위 디렉터리가 있는 곳)
+
+- 문자열로 변환된 경로---위와 동일하지만, `pathlib` 객체가 아닌 문자열로 경로를 반환합니다:
+
+ - `test_file_path_str`
+ - `test_file_dir_str`
+ - `tests_dir_str`
+ - `examples_dir_str`
+ - `repo_root_dir_str`
+ - `src_dir_str`
+
+위의 내용을 사용하려면 테스트가 'transformers.test_utils.TestCasePlus'의 서브클래스에 있는지 확인해야 합니다.
+예를 들어 다음과 같습니다:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class PathExampleTest(TestCasePlus):
+ def test_something_involving_local_locations(self):
+ data_dir = self.tests_dir / "fixtures/tests_samples/wmt_en_ro"
+```
+
+만약 `pathlib`를 통해 경로를 조작할 필요가 없거나 경로를 문자열로만 필요로 하는 경우에는 `pathlib` 객체에 `str()`을 호출하거나 `_str`로 끝나는 접근자를 사용할 수 있습니다.
+예를 들어 다음과 같습니다:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class PathExampleTest(TestCasePlus):
+ def test_something_involving_stringified_locations(self):
+ examples_dir = self.examples_dir_str
+```
+
+### 임시 파일 및 디렉터리[[temporary-files-and-directories]]
+
+고유한 임시 파일 및 디렉터리를 사용하는 것은 병렬 테스트 실행에 있어 필수적입니다.
+이렇게 함으로써 테스트들이 서로의 데이터를 덮어쓰지 않게 할 수 있습니다. 또한 우리는 생성된 테스트의 종료 단계에서 이러한 임시 파일 및 디렉터리를 제거하고 싶습니다.
+따라서 이러한 요구 사항을 충족시켜주는 `tempfile`과 같은 패키지를 사용하는 것이 중요합니다.
+
+그러나 테스트를 디버깅할 때는 임시 파일이나 디렉터리에 들어가는 내용을 확인할 수 있어야 하며,
+재실행되는 각 테스트마다 임시 파일이나 디렉터리의 경로에 대해 무작위 값이 아닌 정확한 값을 알고 싶을 것입니다.
+
+`transformers.test_utils.TestCasePlus`라는 도우미 클래스는 이러한 목적에 가장 적합합니다.
+이 클래스는 `unittest.TestCase`의 하위 클래스이므로, 우리는 이것을 테스트 모듈에서 쉽게 상속할 수 있습니다.
+
+다음은 해당 클래스를 사용하는 예시입니다:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class ExamplesTests(TestCasePlus):
+ def test_whatever(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+```
+
+이 코드는 고유한 임시 디렉터리를 생성하고 `tmp_dir`을 해당 위치로 설정합니다.
+
+- 고유한 임시 디렉터리를 생성합니다:
+
+```python
+def test_whatever(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+```
+
+`tmp_dir`에는 생성된 임시 디렉터리의 경로가 포함됩니다.
+이는 테스트의 종료 단계에서 자동으로 제거됩니다.
+
+- 선택한 경로로 임시 디렉터리 생성 후에 테스트 시작 전에 비어 있는 상태인지 확인하고, 테스트 후에는 비우지 마세요.
+
+```python
+def test_whatever(self):
+ tmp_dir = self.get_auto_remove_tmp_dir("./xxx")
+```
+
+이것은 디버깅할 때 특정 디렉터리를 모니터링하고,
+그 디렉터리에 이전에 실행된 테스트가 데이터를 남기지 않도록 하는 데에 유용합니다.
+
+- `before` 및 `after` 인수를 직접 오버라이딩하여 기본 동작을 변경할 수 있으며
+다음 중 하나의 동작으로 이어집니다:
+
+ - `before=True`: 테스트 시작 시 임시 디렉터리가 항상 지워집니다.
+ - `before=False`: 임시 디렉터리가 이미 존재하는 경우 기존 파일은 그대로 남습니다.
+ - `after=True`: 테스트 종료 시 임시 디렉터리가 항상 삭제됩니다.
+ - `after=False`: 테스트 종료 시 임시 디렉터리가 항상 그대로 유지됩니다.
+
+
+
+`rm -r`에 해당하는 명령을 안전하게 실행하기 위해,
+명시적인 `tmp_dir`을 사용하는 경우 프로젝트 저장소 체크 아웃의 하위 디렉터리만 허용됩니다.
+따라서 실수로 `/tmp`가 아닌 중요한 파일 시스템의 일부가 삭제되지 않도록 항상 `./`로 시작하는 경로를 전달해야 합니다.
+
+
+
+
+
+각 테스트는 여러 개의 임시 디렉터리를 등록할 수 있으며,
+별도로 요청하지 않는 한 모두 자동으로 제거됩니다.
+
+
+
+### 임시 sys.path 오버라이드[[temporary-sys.path-override]]
+
+`sys.path`를 다른 테스트로 임시로 오버라이드하기 위해 예를 들어 `ExtendSysPath` 컨텍스트 관리자를 사용할 수 있습니다.
+예를 들어 다음과 같습니다:
+
+
+```python
+import os
+from transformers.testing_utils import ExtendSysPath
+
+bindir = os.path.abspath(os.path.dirname(__file__))
+with ExtendSysPath(f"{bindir}/.."):
+ from test_trainer import TrainerIntegrationCommon # noqa
+```
+
+### 테스트 건너뛰기[[skipping-tests]]
+
+이것은 버그가 발견되어 새로운 테스트가 작성되었지만 아직 그 버그가 수정되지 않은 경우에 유용합니다.
+이 테스트를 주 저장소에 커밋하려면 `make test` 중에 건너뛰도록 해야 합니다.
+
+방법:
+
+- **skip**은 테스트가 일부 조건이 충족될 경우에만 통과될 것으로 예상되고, 그렇지 않으면 pytest가 전체 테스트를 건너뛰어야 함을 의미합니다.
+일반적인 예로는 Windows가 아닌 플랫폼에서 Windows 전용 테스트를 건너뛰거나
+외부 리소스(예를 들어 데이터베이스)에 의존하는 테스트를 건너뛰는 것이 있습니다.
+
+- **xfail**은 테스트가 특정한 이유로 인해 실패할 것으로 예상하는 것을 의미합니다.
+일반적인 예로는 아직 구현되지 않은 기능이나 아직 수정되지 않은 버그의 테스트가 있습니다.
+`xfail`로 표시된 테스트가 예상대로 실패하지 않고 통과된 경우, 이것은 xpass이며 테스트 결과 요약에 기록됩니다.
+
+두 가지 중요한 차이점 중 하나는 `skip`은 테스트를 실행하지 않지만 `xfail`은 실행한다는 것입니다.
+따라서 오류가 있는 코드가 일부 테스트에 영향을 미칠 수 있는 경우 `xfail`을 사용하지 마세요.
+
+#### 구현[[implementation]]
+
+- 전체 테스트를 무조건 건너뛰려면 다음과 같이 할 수 있습니다:
+
+```python no-style
+@unittest.skip(reason="this bug needs to be fixed")
+def test_feature_x():
+```
+
+또는 pytest를 통해:
+
+```python no-style
+@pytest.mark.skip(reason="this bug needs to be fixed")
+```
+
+또는 `xfail` 방식으로:
+
+```python no-style
+@pytest.mark.xfail
+def test_feature_x():
+```
+
+- 테스트 내부에서 내부 확인에 따라 테스트를 건너뛰는 방법은 다음과 같습니다:
+
+```python
+def test_feature_x():
+ if not has_something():
+ pytest.skip("unsupported configuration")
+```
+
+또는 모듈 전체:
+
+```python
+import pytest
+
+if not pytest.config.getoption("--custom-flag"):
+ pytest.skip("--custom-flag is missing, skipping tests", allow_module_level=True)
+```
+
+또는 `xfail` 방식으로:
+
+```python
+def test_feature_x():
+ pytest.xfail("expected to fail until bug XYZ is fixed")
+```
+
+- import가 missing된 모듈이 있을 때 그 모듈의 모든 테스트를 건너뛰는 방법:
+
+```python
+docutils = pytest.importorskip("docutils", minversion="0.3")
+```
+
+- 조건에 따라 테스트를 건너뛰는 방법:
+
+```python no-style
+@pytest.mark.skipif(sys.version_info < (3,6), reason="requires python3.6 or higher")
+def test_feature_x():
+```
+
+또는:
+
+```python no-style
+@unittest.skipIf(torch_device == "cpu", "Can't do half precision")
+def test_feature_x():
+```
+
+또는 모듈 전체를 건너뛰는 방법:
+
+```python no-style
+@pytest.mark.skipif(sys.platform == 'win32', reason="does not run on windows")
+class TestClass():
+ def test_feature_x(self):
+```
+
+보다 자세한 예제 및 방법은 [여기](https://docs.pytest.org/en/latest/skipping.html)에서 확인할 수 있습니다.
+
+### 느린 테스트[[slow-tests]]
+
+테스트 라이브러리는 지속적으로 확장되고 있으며, 일부 테스트는 실행하는 데 몇 분이 걸립니다.
+그리고 우리에게는 테스트 스위트가 CI를 통해 완료되기까지 한 시간을 기다릴 여유가 없습니다.
+따라서 필수 테스트를 위한 일부 예외를 제외하고 느린 테스트는 다음과 같이 표시해야 합니다.
+
+```python no-style
+from transformers.testing_utils import slow
+@slow
+def test_integration_foo():
+```
+
+`@slow`로 표시된 테스트를 실행하려면 `RUN_SLOW=1` 환경 변수를 설정하세요. 예를 들어 다음과 같습니다:
+
+```bash
+RUN_SLOW=1 pytest tests
+```
+
+`@parameterized`와 같은 몇 가지 데코레이터는 테스트 이름을 다시 작성합니다.
+그러므로 `@slow`와 나머지 건너뛰기 데코레이터 `@require_*`가 올바르게 작동되려면 마지막에 나열되어야 합니다. 다음은 올바른 사용 예입니다.
+
+```python no-style
+@parameterized.expand(...)
+@slow
+def test_integration_foo():
+```
+
+이 문서의 초반부에 설명된 것처럼 느린 테스트는 PR의 CI 확인이 아닌 예약된 일정 기반으로 실행됩니다.
+따라서 PR 제출 중에 일부 문제를 놓친 채로 병합될 수 있습니다.
+이러한 문제들은 다음번의 예정된 CI 작업 중에 감지됩니다.
+하지만 PR을 제출하기 전에 자신의 컴퓨터에서 느린 테스트를 실행하는 것 또한 중요합니다.
+
+느린 테스트로 표시해야 하는지 여부를 결정하는 대략적인 결정 기준은 다음과 같습니다.
+
+만약 테스트가 라이브러리의 내부 구성 요소 중 하나에 집중되어 있다면(예: 모델링 파일, 토큰화 파일, 파이프라인),
+해당 테스트를 느린 테스트 스위트에서 실행해야 합니다.
+만약 라이브러리의 다른 측면(예: 문서 또는 예제)에 집중되어 있다면,
+해당 테스트를 느린 테스트 스위트에서 실행해야 합니다. 그리고 이 접근 방식을 보완하기 위해 예외를 만들어야 합니다.
+
+- 무거운 가중치 세트나 50MB보다 큰 데이터셋을 다운로드해야 하는 모든 테스트(예: 모델 통합 테스트, 토크나이저 통합 테스트, 파이프라인 통합 테스트)를
+ 느린 테스트로 설정해야 합니다.
+ 새로운 모델을 추가하는 경우 통합 테스트용으로 무작위 가중치로 작은 버전을 만들어 허브에 업로드해야 합니다.
+ 이 내용은 아래 단락에서 설명됩니다.
+- 특별히 빠르게 실행되도록 최적화되지 않은 학습을 수행해야 하는 테스트는 느린 테스트로 설정해야 합니다.
+- 느리지 않아야 할 테스트 중 일부가 극도로 느린 경우
+ 예외를 도입하고 이를 `@slow`로 설정할 수 있습니다.
+ 대용량 파일을 디스크에 저장하고 불러오는 자동 모델링 테스트는 `@slow`으로 표시된 테스트의 좋은 예입니다.
+- CI에서 1초 이내에 테스트가 완료되는 경우(다운로드 포함)에는 느린 테스트가 아니어야 합니다.
+
+느린 테스트가 아닌 경우에는 다양한 내부를 완전히 커버하면서 빠르게 유지되어야 합니다.
+예를 들어, 무작위 가중치를 사용하여 특별히 생성된 작은 모델로 테스트하면 상당한 커버리지를 얻을 수 있습니다.
+이러한 모델은 최소한의 레이어 수(예: 2), 어휘 크기(예: 1000) 등의 요소만 가집니다. 그런 다음 `@slow` 테스트는 대형 느린 모델을 사용하여 정성적인 테스트를 수행할 수 있습니다.
+이러한 작은 모델을 사용하는 방법을 확인하려면 다음과 같이 *tiny* 모델을 찾아보세요.
+
+```bash
+grep tiny tests examples
+```
+
+다음은 작은 모델[stas/tiny-wmt19-en-de](https://huggingface.co/stas/tiny-wmt19-en-de)을 만든
+[script](https://github.com/huggingface/transformers/tree/main/scripts/fsmt/fsmt-make-tiny-model.py) 예시입니다.
+특정 모델의 아키텍처에 맞게 쉽게 조정할 수 있습니다.
+
+예를 들어 대용량 모델을 다운로드하는 경우 런타임을 잘못 측정하기 쉽지만,
+로컬에서 테스트하면 다운로드한 파일이 캐시되어 다운로드 시간이 측정되지 않습니다.
+대신 CI 로그의 실행 속도 보고서를 확인하세요(`pytest --durations=0 tests`의 출력).
+
+이 보고서는 느린 이상값으로 표시되지 않거나 빠르게 다시 작성해야 하는 느린 이상값을 찾는 데도 유용합니다.
+CI에서 테스트 스위트가 느려지기 시작하면 이 보고서의 맨 위 목록에 가장 느린 테스트가 표시됩니다.
+
+
+
+### stdout/stderr 출력 테스트[[testing-the-stdout/stderr-output]]
+
+`stdout` 및/또는 `stderr`로 쓰는 함수를 테스트하려면 `pytest`의 [capsys 시스템](https://docs.pytest.org/en/latest/capture.html)을 사용하여 해당 스트림에 액세스할 수 있습니다.
+다음과 같이 수행할 수 있습니다.
+
+```python
+import sys
+
+
+def print_to_stdout(s):
+ print(s)
+
+
+def print_to_stderr(s):
+ sys.stderr.write(s)
+
+
+def test_result_and_stdout(capsys):
+ msg = "Hello"
+ print_to_stdout(msg)
+ print_to_stderr(msg)
+ out, err = capsys.readouterr() # 캡처된 출력 스트림 사용
+ # 선택 사항: 캡처된 스트림 재생성
+ sys.stdout.write(out)
+ sys.stderr.write(err)
+ # 테스트:
+ assert msg in out
+ assert msg in err
+```
+
+그리고, 물론 대부분의 경우에는 `stderr`는 예외의 일부로 제공됩니다.
+그러므로 해당 경우에는 try/except를 사용해야 합니다.
+
+```python
+def raise_exception(msg):
+ raise ValueError(msg)
+
+
+def test_something_exception():
+ msg = "Not a good value"
+ error = ""
+ try:
+ raise_exception(msg)
+ except Exception as e:
+ error = str(e)
+ assert msg in error, f"{msg} is in the exception:\n{error}"
+```
+
+`stdout`를 캡처하는 또 다른 방법은 `contextlib.redirect_stdout`를 사용하는 것입니다.
+
+```python
+from io import StringIO
+from contextlib import redirect_stdout
+
+
+def print_to_stdout(s):
+ print(s)
+
+
+def test_result_and_stdout():
+ msg = "Hello"
+ buffer = StringIO()
+ with redirect_stdout(buffer):
+ print_to_stdout(msg)
+ out = buffer.getvalue()
+ # 선택 사항: 캡처된 스트림 재생성
+ sys.stdout.write(out)
+ # 테스트:
+ assert msg in out
+```
+
+`stdout` 캡처에 관련된 중요한 문제 중 하나는 보통 `print`에서 이전에 인쇄된 내용을 재설정하는 `\r` 문자가 포함될 수 있다는 것입니다.
+`pytest`에서는 문제가 없지만 `pytest -s`에서는 이러한 문자가 버퍼에 포함되므로
+`-s`가 있거나 없는 상태에서 태스트를 수행할 수 있으려면 캡처된 출력에 대해 추가적인 정리가 필요합니다.
+이 경우에는 `re.sub(r'~.*\r', '', buf, 0, re.M)`을 사용할 수 있습니다.
+
+하지만 도우미 컨텍스트 관리자 래퍼를 사용하면
+출력에 `\r`이 포함되어 있는지의 여부에 관계없이 모든 것을 자동으로 처리하므로 편리합니다.
+
+```python
+from transformers.testing_utils import CaptureStdout
+
+with CaptureStdout() as cs:
+ function_that_writes_to_stdout()
+print(cs.out)
+```
+
+다음은 전체 테스트 예제입니다.
+
+```python
+from transformers.testing_utils import CaptureStdout
+
+msg = "Secret message\r"
+final = "Hello World"
+with CaptureStdout() as cs:
+ print(msg + final)
+assert cs.out == final + "\n", f"captured: {cs.out}, expecting {final}"
+```
+
+`stderr`를 캡처하고 싶다면, 대신 `CaptureStderr` 클래스를 사용하세요.
+
+```python
+from transformers.testing_utils import CaptureStderr
+
+with CaptureStderr() as cs:
+ function_that_writes_to_stderr()
+print(cs.err)
+```
+
+두 스트림을 동시에 캡처해야 한다면, 부모 `CaptureStd` 클래스를 사용하세요.
+
+```python
+from transformers.testing_utils import CaptureStd
+
+with CaptureStd() as cs:
+ function_that_writes_to_stdout_and_stderr()
+print(cs.err, cs.out)
+```
+
+또한, 테스트의 디버깅을 지원하기 위해
+이러한 컨텍스트 관리자는 기본적으로 컨텍스트에서 종료할 때 캡처된 스트림을 자동으로 다시 실행합니다.
+
+
+### 로거 스트림 캡처[[capturing-logger-stream]]
+
+로거 출력을 검증해야 하는 경우 `CaptureLogger`를 사용할 수 있습니다.
+
+```python
+from transformers import logging
+from transformers.testing_utils import CaptureLogger
+
+msg = "Testing 1, 2, 3"
+logging.set_verbosity_info()
+logger = logging.get_logger("transformers.models.bart.tokenization_bart")
+with CaptureLogger(logger) as cl:
+ logger.info(msg)
+assert cl.out, msg + "\n"
+```
+
+### 환경 변수를 이용하여 테스트[[testing-with-environment-variables]]
+
+특정 테스트의 환경 변수 영향을 검증하려면
+`transformers.testing_utils.mockenv`라는 도우미 데코레이터를 사용할 수 있습니다.
+
+```python
+from transformers.testing_utils import mockenv
+
+
+class HfArgumentParserTest(unittest.TestCase):
+ @mockenv(TRANSFORMERS_VERBOSITY="error")
+ def test_env_override(self):
+ env_level_str = os.getenv("TRANSFORMERS_VERBOSITY", None)
+```
+
+일부 경우에는 외부 프로그램을 호출해야할 수도 있는데, 이 때에는 여러 개의 로컬 경로를 포함하는 `os.environ`에서 `PYTHONPATH`의 설정이 필요합니다.
+헬퍼 클래스 `transformers.test_utils.TestCasePlus`가 도움이 됩니다:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class EnvExampleTest(TestCasePlus):
+ def test_external_prog(self):
+ env = self.get_env()
+ # 이제 `env`를 사용하여 외부 프로그램 호출
+```
+
+테스트 파일이 `tests` 테스트 스위트 또는 `examples`에 있는지에 따라
+`env[PYTHONPATH]`가 두 디렉터리 중 하나를 포함하도록 설정되며,
+현재 저장소에 대해 테스트가 수행되도록 `src` 디렉터리도 포함됩니다.
+테스트 호출 이전에 설정된 경우에는 `env[PYTHONPATH]`를 그대로 사용합니다.
+
+이 헬퍼 메소드는 `os.environ` 객체의 사본을 생성하므로 원본은 그대로 유지됩니다.
+
+
+### 재현 가능한 결과 얻기[[getting-reproducible-results]]
+
+일부 상황에서 테스트에서 임의성을 제거하여 동일하게 재현 가능한 결과를 얻고 싶을 수 있습니다.
+이를 위해서는 다음과 같이 시드를 고정해야 합니다.
+
+```python
+seed = 42
+
+# 파이썬 RNG
+import random
+
+random.seed(seed)
+
+# 파이토치 RNG
+import torch
+
+torch.manual_seed(seed)
+torch.backends.cudnn.deterministic = True
+if torch.cuda.is_available():
+ torch.cuda.manual_seed_all(seed)
+
+# 넘파이 RNG
+import numpy as np
+
+np.random.seed(seed)
+
+# 텐서플로 RNG
+tf.random.set_seed(seed)
+```
+
+### 테스트 디버깅[[debugging tests]]
+
+경고가 있는 곳에서 디버거를 시작하려면 다음을 수행하세요.
+
+```bash
+pytest tests/utils/test_logging.py -W error::UserWarning --pdb
+```
+
+## Github Actions 워크플로우 작업 처리[[working-with-github-actions-workflows]]
+
+셀프 푸시 워크플로우 CI 작업을 트리거하려면, 다음을 수행해야 합니다.
+
+1. `transformers` 원본에서 새 브랜치를 만듭니다(포크가 아닙니다!).
+2. 브랜치 이름은 `ci_` 또는 `ci-`로 시작해야 합니다(`main`도 트리거하지만 `main`에서는 PR을 할 수 없습니다).
+ 또한 특정 경로에 대해서만 트리거되므로 이 문서가 작성된 후에 변경된 내용은
+ [여기](https://github.com/huggingface/transformers/blob/main/.github/workflows/self-push.yml)의 *push:*에서 확인할 수 있습니다.
+3. 이 브랜치에서 PR을 생성합니다
+4. 그런 다음 [여기](https://github.com/huggingface/transformers/actions/workflows/self-push.yml)에서 작업이 나타나는지 확인할 수 있습니다.
+ 백로그가 있는 경우, 바로 실행되지 않을 수도 있습니다.
+
+
+
+
+## 실험적인 CI 기능 테스트[[testing-Experimental-CI-Features]]
+
+CI 기능을 테스트하는 것은 일반 CI 작동에 방해가 될 수 있기 때문에 잠재적으로 문제가 발생할 수 있습니다.
+따라서 새로운 CI 기능을 추가하는 경우 다음과 같이 수행해야 합니다.
+
+1. 테스트해야 할 내용을 테스트하는 새로운 전용 작업을 생성합니다.
+2. 새로운 작업은 항상 성공해야만 녹색 ✓를 받을 수 있습니다(아래에 자세한 내용이 있습니다).
+3. 다양한 PR 유형에 대한 확인을 위해
+ (사용자 포크 브랜치, 포크되지 않은 브랜치, github.com UI 직접 파일 편집에서 생성된 브랜치, 강제 푸시 등 PR의 유형은 아주 다양합니다.)
+ 며칠 동안 실험 작업의 로그를 모니터링하면서 실행해봅니다.
+ (의도적으로 항상 녹색을 표시하므로 작업 전체가 녹색은 아니라는 점에 유의합니다.)
+4. 모든 것이 안정적인지 확인한 후, 새로운 변경 사항을 기존 작업에 병합합니다.
+
+이렇게 하면 CI 기능 자체에 대한 실험이 일반 작업 흐름에 방해가 되지 않습니다.
+
+그러나 새로운 CI 기능이 개발 중인 동안, 항상 성공하도록 할 수 있는 방법은 무엇일까요?
+
+TravisCI와 같은 일부 CI는 `ignore-step-failure`를 지원하며 전체 작업을 성공한 것으로 보고하지만,
+현재 우리가 사용하는 CircleCI와 Github Actions는 이를 지원하지 않습니다.
+
+따라서 다음과 같은 해결책을 사용할 수 있습니다.
+
+1. bash 스크립트에서 가능한 많은 오류를 억제하기 위해 실행 명령의 시작 부분에 `set +euo pipefail`을 추가합니다.
+2. 마지막 명령은 반드시 성공해야 합니다. `echo "done"` 또는 `true`를 사용하면 됩니다.
+
+예시는 다음과 같습니다.
+
+```yaml
+- run:
+ name: run CI experiment
+ command: |
+ set +euo pipefail
+ echo "setting run-all-despite-any-errors-mode"
+ this_command_will_fail
+ echo "but bash continues to run"
+ # emulate another failure
+ false
+ # but the last command must be a success
+ echo "during experiment do not remove: reporting success to CI, even if there were failures"
+```
+
+간단한 명령의 경우 다음과 같이 수행할 수도 있습니다.
+
+```bash
+cmd_that_may_fail || true
+```
+
+결과에 만족한 후에는 물론, 실험적인 단계 또는 작업을 일반 작업의 나머지 부분과 통합하면서
+`set +euo pipefail` 또는 기타 추가한 요소를 제거하여
+실험 작업이 일반 CI 작동에 방해되지 않도록 해야 합니다.
+
+이 전반적인 과정은 실험 단계가 PR의 전반적인 상태에 영향을 주지 않고 실패하도록
+`allow-failure`와 같은 기능을 설정할 수 있다면 훨씬 더 쉬웠을 것입니다.
+그러나 앞에서 언급한 바와 같이 CircleCI와 Github Actions는 현재 이러한 기능들 지원하지 않습니다.
+
+이 기능의 지원을 위한 투표에 참여하고 CI 관련 스레드들에서 이러한 상황을 확인할 수도 있습니다.
+
+- [Github Actions:](https://github.com/actions/toolkit/issues/399)
+- [CircleCI:](https://ideas.circleci.com/ideas/CCI-I-344)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tf_xla.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tf_xla.md
new file mode 100644
index 0000000000000000000000000000000000000000..0b47d6fbad89d61dd4708285ab7960165e2124ca
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tf_xla.md
@@ -0,0 +1,174 @@
+
+
+# TensorFlow 모델을 위한 XLA 통합 [[xla-integration-for-tensorflow-models]]
+
+[[open-in-colab]]
+
+XLA(Accelerated Linear Algebra)는 TensorFlow 모델의 실행 시간을 가속화하기 위한 컴파일러입니다. [공식 문서](https://www.tensorflow.org/xla)에 따르면 다음과 같습니다:
+
+XLA(Accelerated Linear Algebra)는 선형 대수를 위한 도메인 특화 컴파일러로, TensorFlow 모델을 소스 코드 변경 없이 가속화할 수 있습니다.
+
+TensorFlow에서 XLA를 사용하는 것은 간단합니다. XLA는 `tensorflow` 라이브러리 내에 패키지로 제공되며, [`tf.function`](https://www.tensorflow.org/guide/intro_to_graphs)과 같은 그래프 생성 함수에서 `jit_compile` 인수를 사용하여 활성화할 수 있습니다. `fit()` 및 `predict()`와 같은 Keras 메소드를 사용하는 경우, `jit_compile` 인수를 `model.compile()`에 전달하여 XLA를 간단하게 활성화할 수 있습니다. 그러나 XLA는 이러한 메소드에 국한되지 않고 임의의 `tf.function`을 가속화하는 데에도 사용할 수 있습니다.
+
+🤗 Transformers에서는 [GPT2](https://huggingface.co/docs/transformers/model_doc/gpt2), [T5](https://huggingface.co/docs/transformers/model_doc/t5), [OPT](https://huggingface.co/docs/transformers/model_doc/opt)와 같은 모델의 텍스트 생성, 그리고 [Whisper](https://huggingface.co/docs/transformers/model_doc/whisper)와 같은 모델의 음성 처리를 포함하여 여러 TensorFlow 메소드가 XLA와 호환되도록 다시 작성되었습니다.
+
+정확한 속도 향상은 모델에 따라 다르지만, 🤗 Transformers 내의 TensorFlow 텍스트 생성 모델의 경우 최대 100배의 속도 향상을 확인했습니다. 이 문서에서는 이러한 모델에 대해 XLA를 사용하여 최대 성능을 얻는 방법을 설명합니다. 또한 XLA 통합의 벤치마크 및 디자인 철학에 대한 추가 자료 링크도 제공할 것입니다.
+
+## XLA를 사용하여 TF 함수 실행하기 [[running-tf-functions-with-xla]]
+
+TensorFlow에서 다음과 같은 모델을 고려해 봅시다:
+
+```py
+import tensorflow as tf
+
+model = tf.keras.Sequential(
+ [tf.keras.layers.Dense(10, input_shape=(10,), activation="relu"), tf.keras.layers.Dense(5, activation="softmax")]
+)
+```
+
+위 모델은 차원이 `(10, )`인 입력을 받습니다. 다음과 같이 모델을 사용하여 순전파를 실행할 수 있습니다:
+
+```py
+# 모델에 대한 임의의 입력을 생성합니다.
+batch_size = 16
+input_vector_dim = 10
+random_inputs = tf.random.normal((batch_size, input_vector_dim))
+
+# 순전파를 실행합니다.
+_ = model(random_inputs)
+```
+
+XLA로 컴파일된 함수로 순전파를 실행하려면 다음과 같이 해야 합니다:
+
+```py
+xla_fn = tf.function(model, jit_compile=True)
+_ = xla_fn(random_inputs)
+```
+
+`model`의 기본 `call()` 함수는 XLA 그래프를 컴파일하는 데 사용됩니다. 그러나 다른 모델 함수를 XLA로 컴파일하려면 다음과 같이 할 수도 있습니다:
+
+```py
+my_xla_fn = tf.function(model.my_xla_fn, jit_compile=True)
+```
+
+## 🤗 Transformers에서 XLA를 사용하여 TF 텍스트 생성 모델 실행하기 [[running-a-tf-text-generation-model-with-xla-from-transformers]]
+
+🤗 Transformers에서 XLA로 가속화된 생성을 활성화하려면 최신 버전의 `transformers`가 설치되어 있어야 합니다. 다음과 같이 설치할 수 있습니다:
+
+```bash
+pip install transformers --upgrade
+```
+
+그리고 다음 코드를 실행할 수 있습니다:
+
+```py
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+# 최소 버전의 Transformers가 설치되어 있지 않다면 오류가 발생합니다.
+from transformers.utils import check_min_version
+
+check_min_version("4.21.0")
+
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+input_string = ["TensorFlow is"]
+
+# XLA 생성 함수를 만들기 위한 한 줄
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+tokenized_input = tokenizer(input_string, return_tensors="tf")
+generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+
+decoded_text = tokenizer.decode(generated_tokens[0], skip_special_tokens=True)
+print(f"Generated -- {decoded_text}")
+# Generated -- TensorFlow is an open-source, open-source, distributed-source application # framework for the
+```
+
+알 수 있듯이, `generate()`에서 XLA를 활성화하는 것은 단 한 줄의 코드입니다. 코드의 나머지 부분은 변경되지 않습니다. 그러나 위 코드 스니펫에서는 XLA에 특정한 몇 가지 주의할 점이 있습니다. XLA가 가져다줄 속도 향상을 실현하기 위해서는 이를 알고 있어야 합니다. 다음 섹션에서 이에 대해 논의합니다.
+
+## 주의할 점 [[gotchas-to-be-aware-of]]
+
+XLA 활성화 함수(`xla_generate()`와 같은)를 처음 실행할 때 내부적으로 계산 그래프를 추론하려고 하며, 이는 시간이 소요됩니다. 이 과정은 [“추적(tracing)”](https://www.tensorflow.org/guide/intro_to_graphs#when_is_a_function_tracing)이라고 알려져 있습니다.
+
+생성 시간이 빠르지 않다는 것을 알 수 있을 것입니다. `xla_generate()`(또는 다른 XLA 활성화 함수)의 연속 호출은 함수에 전달된 입력이 초기에 구축된 계산 그래프와 동일한 형태를 따른다면, 계산 그래프를 추론할 필요가 없습니다. 이는 입력 형태가 고정된 모달리티(예: 이미지)에는 문제가 되지 않지만, 가변 입력 형태 모달리티(예: 텍스트)를 사용할 때 주의해야 합니다.
+
+`xla_generate()`가 항상 동일한 입력 형태로 동작하도록 하려면, 토크나이저를 호출할 때 `padding` 인수를 지정할 수 있습니다.
+
+```py
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+input_string = ["TensorFlow is"]
+
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+# 여기서, padding 옵션이 있는 토크나이저를 호출합니다.
+tokenized_input = tokenizer(input_string, pad_to_multiple_of=8, padding=True, return_tensors="tf")
+
+generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+decoded_text = tokenizer.decode(generated_tokens[0], skip_special_tokens=True)
+print(f"Generated -- {decoded_text}")
+```
+
+이렇게 하면 `xla_generate()`에 대한 입력이 항상 추적된 형태로 전달되어 생성 시간이 가속화됩니다. 다음 코드로 이를 확인할 수 있습니다:
+
+```py
+import time
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+for input_string in ["TensorFlow is", "TensorFlow is a", "TFLite is a"]:
+ tokenized_input = tokenizer(input_string, pad_to_multiple_of=8, padding=True, return_tensors="tf")
+ start = time.time_ns()
+ generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+ end = time.time_ns()
+ print(f"Execution time -- {(end - start) / 1e6:.1f} ms\n")
+```
+
+Tesla T4 GPU에서는 다음과 같은 출력을 예상할 수 있습니다:
+
+```bash
+Execution time -- 30819.6 ms
+
+Execution time -- 79.0 ms
+
+Execution time -- 78.9 ms
+```
+`xla_generate()`의 첫 번째 호출은 추적 때문에 시간이 오래 걸리지만, 연속 호출은 몇 배나 빠릅니다. 생성 옵션에 대한 어떤 변경이든 다시 추적을 유발하므로 생성 시간이 느려질 수 있음을 명심하세요.
+
+이 문서에서는 🤗 Transformers에서 제공하는 모든 텍스트 생성 옵션을 다루지 않았습니다. 고급 사용 사례에 대해 문서를 참조하시기 바랍니다.
+
+## 추가 자료 [[additional-resources]]
+
+여기에 🤗 Transformers와 XLA에 대해 더 자세히 알고 싶은 경우 도움이 될 수 있는 몇 가지 추가 자료를 제공합니다.
+
+* [이 Colab 노트북](https://colab.research.google.com/github/huggingface/blog/blob/main/notebooks/91_tf_xla_generate.ipynb)은 XLA와 호환되는 인코더-디코더([T5](https://huggingface.co/docs/transformers/model_doc/t5)와 같은) 및 디코더 전용([GPT2](https://huggingface.co/docs/transformers/model_doc/gpt2)와 같은) 텍스트 생성 모델을 실험해 볼 수 있는 대화형 데모를 제공합니다.
+* [이 블로그 글](https://huggingface.co/blog/tf-xla-generate)은 TensorFlow에서 XLA에 대한 친절한 소개와 함께 XLA와 호환되는 모델의 비교 벤치마크에 대한 개요를 제공합니다.
+* [이 블로그 글](https://blog.tensorflow.org/2022/11/how-hugging-face-improved-text-generation-performance-with-xla.html)은 🤗 Transformers의 TensorFlow 모델에 XLA 지원을 추가하는 것에 대한 디자인 철학을 논의합니다.
+* XLA와 TensorFlow 그래프에 대해 더 자세히 알고 싶은 경우 추천하는 글:
+ * [XLA: 기계 학습을 위한 최적화 컴파일러](https://www.tensorflow.org/xla)
+ * [그래프 및 tf.function 소개](https://www.tensorflow.org/guide/intro_to_graphs)
+ * [tf.function으로 성능 향상하기](https://www.tensorflow.org/guide/function)
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tflite.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tflite.md
new file mode 100644
index 0000000000000000000000000000000000000000..464106a6b7c2612b93a25848b750d90f7258e4cd
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tflite.md
@@ -0,0 +1,62 @@
+
+
+# TFLite로 내보내기[[export-to-tflite]]
+
+[TensorFlow Lite](https://www.tensorflow.org/lite/guide)는 자원이 제한된 휴대폰, 임베디드 시스템, 사물인터넷(IoT) 기기에서
+기계학습 모델을 배포하기 위한 경량 프레임워크입니다.
+TFLite는 연산 능력, 메모리, 전력 소비가 제한된 기기에서 모델을 효율적으로 최적화하고 실행하기 위해
+설계되었습니다.
+TensorFlow Lite 모델은 `.tflite` 파일 확장자로 식별되는 특수하고 효율적인 휴대용 포맷으로 표현됩니다.
+
+🤗 Optimum은 `exporters.tflite` 모듈로 🤗 Transformers 모델을 TFLite로 내보내는 기능을 제공합니다.
+지원되는 모델 아키텍처 목록은 [🤗 Optimum 문서](https://huggingface.co/docs/optimum/exporters/tflite/overview)를 참고하세요.
+
+모델을 TFLite로 내보내려면, 필요한 종속성을 설치하세요:
+
+```bash
+pip install optimum[exporters-tf]
+```
+
+모든 사용 가능한 인수를 확인하려면, [🤗 Optimum 문서](https://huggingface.co/docs/optimum/main/en/exporters/tflite/usage_guides/export_a_model)를 참고하거나
+터미널에서 도움말을 살펴보세요:
+
+```bash
+optimum-cli export tflite --help
+```
+
+예를 들어 🤗 Hub에서의 `google-bert/bert-base-uncased` 모델 체크포인트를 내보내려면, 다음 명령을 실행하세요:
+
+```bash
+optimum-cli export tflite --model google-bert/bert-base-uncased --sequence_length 128 bert_tflite/
+```
+
+다음과 같이 진행 상황을 나타내는 로그와 결과물인 `model.tflite`가 저장된 위치를 보여주는 로그가 표시됩니다:
+
+```bash
+Validating TFLite model...
+ -[✓] TFLite model output names match reference model (logits)
+ - Validating TFLite Model output "logits":
+ -[✓] (1, 128, 30522) matches (1, 128, 30522)
+ -[x] values not close enough, max diff: 5.817413330078125e-05 (atol: 1e-05)
+The TensorFlow Lite export succeeded with the warning: The maximum absolute difference between the output of the reference model and the TFLite exported model is not within the set tolerance 1e-05:
+- logits: max diff = 5.817413330078125e-05.
+ The exported model was saved at: bert_tflite
+ ```
+
+위 예제는 🤗 Hub에서의 체크포인트를 내보내는 방법을 보여줍니다.
+로컬 모델을 내보낸다면, 먼저 모델 가중치와 토크나이저 파일이 모두 같은 디렉터리( `local_path` )에 저장됐는지 확인하세요.
+CLI를 사용할 때, 🤗 Hub에서의 체크포인트 이름 대신 `model` 인수에 `local_path`를 전달하면 됩니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tokenizer_summary.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tokenizer_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..0a4ece29a476d942b6cfc5067f723a301cb2e278
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/tokenizer_summary.md
@@ -0,0 +1,253 @@
+
+
+# 토크나이저 요약[[summary-of-the-tokenizers]]
+
+[[open-in-colab]]
+
+이 페이지에서는 토큰화에 대해 자세히 살펴보겠습니다.
+
+", "ug"]`로 토큰화될 것입니다.
+훈련 데이터에는 단일 문자가 최소한 한 번 등장하기 때문에 일반적으로 `"m"`과 같은 단일 문자는 `""` 기호로 대체되지 않지만, 이모티콘과 같은 특별한 문자인 경우에는 대체될 수 있습니다.
+
+이전에 언급했듯이 어휘 크기(즉 기본 어휘 크기 + 병합 횟수)는 선택해야하는 하이퍼파라미터입니다.
+예를 들어 [GPT](model_doc/gpt)의 기본 어휘 크기는 478, 40,000번의 병합 이후에 훈련을 종료하기 때문에 어휘 크기가 40,478입니다.
+
+#### 바이트 수준 BPE (Byte-level BPE)[[bytelevel-bpe]]
+
+가능한 모든 기본 문자를 포함하는 기본 어휘의 크기는 굉장히 커질 수 있습니다. (예: 모든 유니코드 문자를 기본 문자로 간주하는 경우)
+더 나은 기본 어휘를 갖도록 [GPT-2](https://cdn.openai.com/better-language-models/language_models_are_unsupervised_multitask_learners.pdf)는 기본 어휘로 바이트(bytes)를 사용합니다.
+이 방식은 모든 기본 문자가 어휘에 포함되도록 하면서 기본 어휘의 크기를 256으로 제한합니다.
+구두점을 다루는 추가적인 규칙을 사용해 GPT2 토크나이저는 모든 텍스트를 기호 없이 토큰화할 수 있습니다.
+[GPT-2](model_doc/gpt)의 어휘 크기는 50,257로 256 바이트 크기의 기본 토큰, 특별한 end-of-text 토큰과 50,000번의 병합으로 학습한 기호로 구성됩니다.
+
+
+
+TorchScript를 활용한 실험은 아직 초기 단계로, 가변적인 입력 크기 모델들을 통해 그 기능성을 계속 탐구하고 있습니다.
+이 기능은 저희가 관심을 두고 있는 분야 중 하나이며,
+앞으로 출시될 버전에서 더 많은 코드 예제, 더 유연한 구현, 그리고 Python 기반 코드와 컴파일된 TorchScript를 비교하는 벤치마크를 등을 통해 분석을 심화할 예정입니다.
+
+
+
+[TorchScript 문서](https://pytorch.org/docs/stable/jit.html)에서는 이렇게 말합니다.
+
+> TorchScript는 PyTorch 코드에서 직렬화 및 최적화 가능한 모델을 생성하는 방법입니다.
+
+[JIT과 TRACE](https://pytorch.org/docs/stable/jit.html)는 개발자가 모델을 내보내서 효율 지향적인 C++ 프로그램과 같은 다른 프로그램에서 재사용할 수 있도록 하는 PyTorch 모듈입니다.
+
+PyTorch 기반 Python 프로그램과 다른 환경에서 모델을 재사용할 수 있도록, 🤗 Transformers 모델을 TorchScript로 내보낼 수 있는 인터페이스를 제공합니다.
+이 문서에서는 TorchScript를 사용하여 모델을 내보내고 사용하는 방법을 설명합니다.
+
+모델을 내보내려면 두 가지가 필요합니다:
+
+- `torchscript` 플래그로 모델 인스턴스화
+- 더미 입력을 사용한 순전파(forward pass)
+
+이 필수 조건들은 아래에 자세히 설명된 것처럼 개발자들이 주의해야 할 여러 사항들을 의미합니다.
+
+## TorchScript 플래그와 묶인 가중치(tied weights)[[torchscript-flag-and-tied-weights]]
+
+`torchscript` 플래그가 필요한 이유는 대부분의 🤗 Transformers 언어 모델에서 `Embedding` 레이어와 `Decoding` 레이어 간의 묶인 가중치(tied weights)가 존재하기 때문입니다.
+TorchScript는 묶인 가중치를 가진 모델을 내보낼 수 없으므로, 미리 가중치를 풀고 복제해야 합니다.
+
+`torchscript` 플래그로 인스턴스화된 모델은 `Embedding` 레이어와 `Decoding` 레이어가 분리되어 있으므로 이후에 훈련해서는 안 됩니다.
+훈련을 하게 되면 두 레이어 간 동기화가 해제되어 예상치 못한 결과가 발생할 수 있습니다.
+
+언어 모델 헤드를 갖지 않은 모델은 가중치가 묶여 있지 않아서 이 문제가 발생하지 않습니다.
+이러한 모델들은 `torchscript` 플래그 없이 안전하게 내보낼 수 있습니다.
+
+## 더미 입력과 표준 길이[[dummy-inputs-and-standard-lengths]]
+
+더미 입력(dummy inputs)은 모델의 순전파(forward pass)에 사용됩니다.
+입력 값이 레이어를 통해 전파되는 동안, PyTorch는 각 텐서에서 실행된 다른 연산을 추적합니다.
+이러한 기록된 연산은 모델의 *추적(trace)*을 생성하는 데 사용됩니다.
+
+추적은 입력의 차원을 기준으로 생성됩니다.
+따라서 더미 입력의 차원에 제한되어, 다른 시퀀스 길이나 배치 크기에서는 작동하지 않습니다.
+다른 크기로 시도할 경우 다음과 같은 오류가 발생합니다:
+
+```
+`The expanded size of the tensor (3) must match the existing size (7) at non-singleton dimension 2`
+```
+추론 중 모델에 공급될 가장 큰 입력만큼 큰 더미 입력 크기로 모델을 추적하는 것이 좋습니다.
+패딩은 누락된 값을 채우는 데 도움이 될 수 있습니다.
+그러나 모델이 더 큰 입력 크기로 추적되기 때문에, 행렬의 차원이 커지고 계산량이 많아집니다.
+
+다양한 시퀀스 길이 모델을 내보낼 때는 각 입력에 대해 수행되는 총 연산 횟수에 주의하고 성능을 주의 깊게 확인하세요.
+
+## Python에서 TorchScript 사용하기[[using-torchscript-in-python]]
+
+이 섹션에서는 모델을 저장하고 가져오는 방법, 추적을 사용하여 추론하는 방법을 보여줍니다.
+
+### 모델 저장하기[[saving-a-model]]
+
+`BertModel`을 TorchScript로 내보내려면 `BertConfig` 클래스에서 `BertModel`을 인스턴스화한 다음, `traced_bert.pt`라는 파일명으로 디스크에 저장하면 됩니다.
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+
+enc = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+
+# 입력 텍스트 토큰화하기
+text = "[CLS] Who was Jim Henson ? [SEP] Jim Henson was a puppeteer [SEP]"
+tokenized_text = enc.tokenize(text)
+
+# 입력 토큰 중 하나를 마스킹하기
+masked_index = 8
+tokenized_text[masked_index] = "[MASK]"
+indexed_tokens = enc.convert_tokens_to_ids(tokenized_text)
+segments_ids = [0, 0, 0, 0, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1]
+
+# 더미 입력 만들기
+tokens_tensor = torch.tensor([indexed_tokens])
+segments_tensors = torch.tensor([segments_ids])
+dummy_input = [tokens_tensor, segments_tensors]
+
+# torchscript 플래그로 모델 초기화하기
+# 이 모델은 LM 헤드가 없으므로 필요하지 않지만, 플래그를 True로 설정합니다.
+config = BertConfig(
+ vocab_size_or_config_json_file=32000,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ torchscript=True,
+)
+
+# 모델을 인스턴트화하기
+model = BertModel(config)
+
+# 모델을 평가 모드로 두어야 합니다.
+model.eval()
+
+# 만약 *from_pretrained*를 사용하여 모델을 인스턴스화하는 경우, TorchScript 플래그를 쉽게 설정할 수 있습니다
+model = BertModel.from_pretrained("google-bert/bert-base-uncased", torchscript=True)
+
+# 추적 생성하기
+traced_model = torch.jit.trace(model, [tokens_tensor, segments_tensors])
+torch.jit.save(traced_model, "traced_bert.pt")
+```
+
+### 모델 가져오기[[loading-a-model]]
+
+이제 이전에 저장한 `BertModel`, 즉 `traced_bert.pt`를 디스크에서 가져오고, 이전에 초기화한 `dummy_input`에서 사용할 수 있습니다.
+
+```python
+loaded_model = torch.jit.load("traced_bert.pt")
+loaded_model.eval()
+
+all_encoder_layers, pooled_output = loaded_model(*dummy_input)
+```
+
+### 추적된 모델을 사용하여 추론하기[[using-a-traced-model-for-inference]]
+
+`__call__` 이중 언더스코어(dunder) 메소드를 사용하여 추론에 추적된 모델을 사용하세요:
+
+```python
+traced_model(tokens_tensor, segments_tensors)
+```
+
+## Neuron SDK로 Hugging Face TorchScript 모델을 AWS에 배포하기[[deploy-hugging-face-torchscript-models-to-aws-with-the-neuron-sdk]]
+
+AWS가 클라우드에서 저비용, 고성능 머신 러닝 추론을 위한 [Amazon EC2 Inf1](https://aws.amazon.com/ec2/instance-types/inf1/) 인스턴스 제품군을 출시했습니다.
+Inf1 인스턴스는 딥러닝 추론 워크로드에 특화된 맞춤 하드웨어 가속기인 AWS Inferentia 칩으로 구동됩니다.
+[AWS Neuron](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/#)은 Inferentia를 위한 SDK로, Inf1에 배포하기 위한 transformers 모델 추적 및 최적화를 지원합니다.
+Neuron SDK는 다음과 같은 기능을 제공합니다:
+
+1. 코드 한 줄만 변경하면 클라우드 추론를 위해 TorchScript 모델을 추적하고 최적화할 수 있는 쉬운 API
+2. 즉시 사용 가능한 성능 최적화로 [비용 효율 향상](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/benchmark/>)
+3. [PyTorch](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/bert_tutorial/tutorial_pretrained_bert.html) 또는 [TensorFlow](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/tensorflow/huggingface_bert/huggingface_bert.html)로 구축된 Hugging Face transformers 모델 지원
+
+### 시사점[[implications]]
+
+[BERT (Bidirectional Encoder Representations from Transformers)](https://huggingface.co/docs/transformers/main/model_doc/bert) 아키텍처 또는 그 변형인 [distilBERT](https://huggingface.co/docs/transformers/main/model_doc/distilbert) 및 [roBERTa](https://huggingface.co/docs/transformers/main/model_doc/roberta)를 기반으로 한 Transformers 모델은 추출 기반 질의응답, 시퀀스 분류 및 토큰 분류와 같은 비생성 작업 시 Inf1에서 최상의 성능을 보입니다.
+그러나 텍스트 생성 작업도 [AWS Neuron MarianMT 튜토리얼](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/transformers-marianmt.html)을 따라 Inf1에서 실행되도록 조정할 수 있습니다.
+
+Inferentia에서 바로 변환할 수 있는 모델에 대한 자세한 정보는 Neuron 문서의 [Model Architecture Fit](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/models/models-inferentia.html#models-inferentia) 섹션에서 확인할 수 있습니다.
+
+### 종속성[[dependencies]]
+
+AWS Neuron을 사용하여 모델을 변환하려면 [Neuron SDK 환경](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/neuron-frameworks/pytorch-neuron/index.html#installation-guide)이 필요합니다.
+ 이는 [AWS Deep Learning AMI](https://docs.aws.amazon.com/dlami/latest/devguide/tutorial-inferentia-launching.html)에 미리 구성되어 있습니다.
+
+### AWS Neuron으로 모델 변환하기[[converting-a-model-for-aws-neuron]]
+
+`BertModel`을 추적하려면, [Python에서 TorchScript 사용하기](torchscript#using-torchscript-in-python)에서와 동일한 코드를 사용해서 AWS NEURON용 모델을 변환합니다.
+`torch.neuron` 프레임워크 익스텐션을 가져와 Python API를 통해 Neuron SDK의 구성 요소에 접근합니다:
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+import torch.neuron
+```
+
+다음 줄만 수정하면 됩니다:
+
+```diff
+- torch.jit.trace(model, [tokens_tensor, segments_tensors])
++ torch.neuron.trace(model, [token_tensor, segments_tensors])
+```
+
+이로써 Neuron SDK가 모델을 추적하고 Inf1 인스턴스에 최적화할 수 있게 됩니다.
+
+AWS Neuron SDK의 기능, 도구, 예제 튜토리얼 및 최신 업데이트에 대해 자세히 알아보려면 [AWS NeuronSDK 문서](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/index.html)를 참조하세요.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/trainer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/trainer.md
new file mode 100644
index 0000000000000000000000000000000000000000..42789fc0c2f6200a3ae7d6be24f0ae43591ea1f0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/trainer.md
@@ -0,0 +1,596 @@
+
+
+# Trainer [[trainer]]
+
+[`Trainer`]는 Transformers 라이브러리에 구현된 PyTorch 모델을 반복하여 훈련 및 평가 과정입니다. 훈련에 필요한 요소(모델, 토크나이저, 데이터셋, 평가 함수, 훈련 하이퍼파라미터 등)만 제공하면 [`Trainer`]가 필요한 나머지 작업을 처리합니다. 이를 통해 직접 훈련 루프를 작성하지 않고도 빠르게 훈련을 시작할 수 있습니다. 또한 [`Trainer`]는 강력한 맞춤 설정과 다양한 훈련 옵션을 제공하여 사용자 맞춤 훈련이 가능합니다.
+
+
+
+Transformers는 [`Trainer`] 클래스 외에도 번역이나 요약과 같은 시퀀스-투-시퀀스 작업을 위한 [`Seq2SeqTrainer`] 클래스도 제공합니다. 또한 [TRL](https://hf.co/docs/trl) 라이브러리에는 [`Trainer`] 클래스를 감싸고 Llama-2 및 Mistral과 같은 언어 모델을 자동 회귀 기법으로 훈련하는 데 최적화된 [`~trl.SFTTrainer`] 클래스 입니다. [`~trl.SFTTrainer`]는 시퀀스 패킹, LoRA, 양자화 및 DeepSpeed와 같은 기능을 지원하여 크기 상관없이 모델 효율적으로 확장할 수 있습니다.
+
+
+
+시작하기 전에, 분산 환경에서 PyTorch 훈련과 실행을 할 수 있게 [Accelerate](https://hf.co/docs/accelerate) 라이브러리가 설치되었는지 확인하세요.
+
+```bash
+pip install accelerate
+
+# 업그레이드
+pip install accelerate --upgrade
+```
+
+이 가이드는 [`Trainer`] 클래스에 대한 개요를 제공합니다.
+
+## 기본 사용법 [[basic-usage]]
+
+[`Trainer`]는 기본적인 훈련 루프에 필요한 모든 코드를 포함하고 있습니다.
+
+1. 손실을 계산하는 훈련 단계를 수행합니다.
+2. [`~accelerate.Accelerator.backward`] 메소드로 그레이디언트를 계산합니다.
+3. 그레이디언트를 기반으로 가중치를 업데이트합니다.
+4. 정해진 에폭 수에 도달할 때까지 이 과정을 반복합니다.
+
+[`Trainer`] 클래스는 PyTorch와 훈련 과정에 익숙하지 않거나 막 시작한 경우에도 훈련이 가능하도록 필요한 모든 코드를 추상화하였습니다. 또한 매번 훈련 루프를 손수 작성하지 않아도 되며, 훈련에 필요한 모델과 데이터셋 같은 필수 구성 요소만 제공하면, [Trainer] 클래스가 나머지를 처리합니다.
+
+훈련 옵션이나 하이퍼파라미터를 지정하려면, [`TrainingArguments`] 클래스에서 확인 할 수 있습니다. 예를 들어, 모델을 저장할 디렉토리를 `output_dir`에 정의하고, 훈련 후에 Hub로 모델을 푸시하려면 `push_to_hub=True`로 설정합니다.
+
+```py
+from transformers import TrainingArguments
+
+training_args = TrainingArguments(
+ output_dir="your-model",
+ learning_rate=2e-5,
+ per_device_train_batch_size=16,
+ per_device_eval_batch_size=16,
+ num_train_epochs=2,
+ weight_decay=0.01,
+ eval_strategy="epoch",
+ save_strategy="epoch",
+ load_best_model_at_end=True,
+ push_to_hub=True,
+)
+```
+
+`training_args`를 [`Trainer`]에 모델, 데이터셋, 데이터셋 전처리 도구(데이터 유형에 따라 토크나이저, 특징 추출기 또는 이미지 프로세서일 수 있음), 데이터 수집기 및 훈련 중 확인할 지표를 계산할 함수를 함께 전달하세요.
+
+마지막으로, [`~Trainer.train`]를 호출하여 훈련을 시작하세요!
+
+```py
+from transformers import Trainer
+
+trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=dataset["train"],
+ eval_dataset=dataset["test"],
+ tokenizer=tokenizer,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics,
+)
+
+trainer.train()
+```
+
+### 체크포인트 [[checkpoints]]
+
+[`Trainer`] 클래스는 [`TrainingArguments`]의 `output_dir` 매개변수에 지정된 디렉토리에 모델 체크포인트를 저장합니다. 체크포인트는 `checkpoint-000` 하위 폴더에 저장되며, 여기서 끝의 숫자는 훈련 단계에 해당합니다. 체크포인트를 저장하면 나중에 훈련을 재개할 때 유용합니다.
+
+```py
+# 최신 체크포인트에서 재개
+trainer.train(resume_from_checkpoint=True)
+
+# 출력 디렉토리에 저장된 특정 체크포인트에서 재개
+trainer.train(resume_from_checkpoint="your-model/checkpoint-1000")
+```
+
+체크포인트를 Hub에 푸시하려면 [`TrainingArguments`]에서 `push_to_hub=True`로 설정하여 커밋하고 푸시할 수 있습니다. 체크포인트 저장 방법을 결정하는 다른 옵션은 [`hub_strategy`](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments.hub_strategy) 매개변수에서 설정합니다:
+
+* `hub_strategy="checkpoint"`는 최신 체크포인트를 "last-checkpoint"라는 하위 폴더에 푸시하여 훈련을 재개할 수 있습니다.
+* `hub_strategy="all_checkpoints"`는 모든 체크포인트를 `output_dir`에 정의된 디렉토리에 푸시합니다(모델 리포지토리에서 폴더당 하나의 체크포인트를 볼 수 있습니다).
+
+체크포인트에서 훈련을 재개할 때, [`Trainer`]는 체크포인트가 저장될 때와 동일한 Python, NumPy 및 PyTorch RNG 상태를 유지하려고 합니다. 하지만 PyTorch는 기본 설정으로 '일관된 결과를 보장하지 않음'으로 많이 되어있기 때문에, RNG 상태가 동일할 것이라고 보장할 수 없습니다. 따라서, 일관된 결과가 보장되도록 활성화 하려면, [랜덤성 제어](https://pytorch.org/docs/stable/notes/randomness#controlling-sources-of-randomness) 가이드를 참고하여 훈련을 완전히 일관된 결과를 보장 받도록 만들기 위해 활성화할 수 있는 항목을 확인하세요. 다만, 특정 설정을 결정적으로 만들면 훈련이 느려질 수 있습니다.
+
+## Trainer 맞춤 설정 [[customize-the-trainer]]
+
+[`Trainer`] 클래스는 접근성과 용이성을 염두에 두고 설계되었지만, 더 다양한 기능을 원하는 사용자들을 위해 다양한 맞춤 설정 옵션을 제공합니다. [`Trainer`]의 많은 메소드는 서브클래스화 및 오버라이드하여 원하는 기능을 제공할 수 있으며, 이를 통해 전체 훈련 루프를 다시 작성할 필요 없이 원하는 기능을 추가할 수 있습니다. 이러한 메소드에는 다음이 포함됩니다:
+
+* [`~Trainer.get_train_dataloader`]는 훈련 데이터로더를 생성합니다.
+* [`~Trainer.get_eval_dataloader`]는 평가 데이터로더를 생성합니다.
+* [`~Trainer.get_test_dataloader`]는 테스트 데이터로더를 생성합니다.
+* [`~Trainer.log`]는 훈련을 모니터링하는 다양한 객체에 대한 정보를 로그로 남깁니다.
+* [`~Trainer.create_optimizer_and_scheduler`]는 `__init__`에서 전달되지 않은 경우 옵티마이저와 학습률 스케줄러를 생성합니다. 이들은 각각 [`~Trainer.create_optimizer`] 및 [`~Trainer.create_scheduler`]로 별도로 맞춤 설정 할 수 있습니다.
+* [`~Trainer.compute_loss`]는 훈련 입력 배치에 대한 손실을 계산합니다.
+* [`~Trainer.training_step`]는 훈련 단계를 수행합니다.
+* [`~Trainer.prediction_step`]는 예측 및 테스트 단계를 수행합니다.
+* [`~Trainer.evaluate`]는 모델을 평가하고 평가 지표을 반환합니다.
+* [`~Trainer.predict`]는 테스트 세트에 대한 예측(레이블이 있는 경우 지표 포함)을 수행합니다.
+
+예를 들어, [`~Trainer.compute_loss`] 메소드를 맞춤 설정하여 가중 손실을 사용하려는 경우:
+
+```py
+from torch import nn
+from transformers import Trainer
+
+class CustomTrainer(Trainer):
+ def compute_loss(self,
+
+ model, inputs, return_outputs=False):
+ labels = inputs.pop("labels")
+ # 순방향 전파
+ outputs = model(**inputs)
+ logits = outputs.get("logits")
+ # 서로 다른 가중치로 3개의 레이블에 대한 사용자 정의 손실을 계산
+ loss_fct = nn.CrossEntropyLoss(weight=torch.tensor([1.0, 2.0, 3.0], device=model.device))
+ loss = loss_fct(logits.view(-1, self.model.config.num_labels), labels.view(-1))
+ return (loss, outputs) if return_outputs else loss
+```
+
+### 콜백 [[callbacks]]
+
+[`Trainer`]를 맞춤 설정하는 또 다른 방법은 [콜백](callbacks)을 사용하는 것입니다. 콜백은 훈련 루프에서 *변화를 주지 않습니다*. 훈련 루프의 상태를 검사한 후 상태에 따라 일부 작업(조기 종료, 결과 로그 등)을 실행합니다. 즉, 콜백은 사용자 정의 손실 함수와 같은 것을 구현하는 데 사용할 수 없으며, 이를 위해서는 [`~Trainer.compute_loss`] 메소드를 서브클래스화하고 오버라이드해야 합니다.
+
+예를 들어, 훈련 루프에 10단계 후 조기 종료 콜백을 추가하려면 다음과 같이 합니다.
+
+```py
+from transformers import TrainerCallback
+
+class EarlyStoppingCallback(TrainerCallback):
+ def __init__(self, num_steps=10):
+ self.num_steps = num_steps
+
+ def on_step_end(self, args, state, control, **kwargs):
+ if state.global_step >= self.num_steps:
+ return {"should_training_stop": True}
+ else:
+ return {}
+```
+
+그런 다음, 이를 [`Trainer`]의 `callback` 매개변수에 전달합니다.
+
+```py
+from transformers import Trainer
+
+trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=dataset["train"],
+ eval_dataset=dataset["test"],
+ tokenizer=tokenizer,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics,
+ callbacks=[EarlyStoppingCallback()],
+)
+```
+
+## 로깅 [[logging]]
+
+
+
+로깅 API에 대한 자세한 내용은 [로깅](./main_classes/logging) API 레퍼런스를 확인하세요.
+
+
+
+[`Trainer`]는 기본적으로 `logging.INFO`로 설정되어 있어 오류, 경고 및 기타 기본 정보를 보고합니다. 분산 환경에서는 [`Trainer`] 복제본이 `logging.WARNING`으로 설정되어 오류와 경고만 보고합니다. [`TrainingArguments`]의 [`log_level`](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments.log_level) 및 [`log_level_replica`](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments.log_level_replica) 매개변수로 로그 레벨을 변경할 수 있습니다.
+
+각 노드의 로그 레벨 설정을 구성하려면 [`log_on_each_node`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.log_on_each_node) 매개변수를 사용하여 각 노드에서 로그 레벨을 사용할지 아니면 주 노드에서만 사용할지 결정하세요.
+
+
+
+[`Trainer`]는 [`Trainer.__init__`] 메소드에서 각 노드에 대해 로그 레벨을 별도로 설정하므로, 다른 Transformers 기능을 사용할 경우 [`Trainer`] 객체를 생성하기 전에 이를 미리 설정하는 것이 좋습니다.
+
+
+
+예를 들어, 메인 코드와 모듈을 각 노드에 따라 동일한 로그 레벨을 사용하도록 설정하려면 다음과 같이 합니다.
+
+```py
+logger = logging.getLogger(__name__)
+
+logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+)
+
+log_level = training_args.get_process_log_level()
+logger.setLevel(log_level)
+datasets.utils.logging.set_verbosity(log_level)
+transformers.utils.logging.set_verbosity(log_level)
+
+trainer = Trainer(...)
+```
+
+각 노드에서 기록될 내용을 구성하기 위해 `log_level`과 `log_level_replica`를 다양한 조합으로 사용해보세요.
+
+
+
+
+```bash
+my_app.py ... --log_level warning --log_level_replica error
+```
+
+
+
+
+멀티 노드 환경에서는 `log_on_each_node 0` 매개변수를 추가합니다.
+
+```bash
+my_app.py ... --log_level warning --log_level_replica error --log_on_each_node 0
+
+# 오류만 보고하도록 설정
+my_app.py ... --log_level error --log_level_replica error --log_on_each_node 0
+```
+
+
+
+
+## NEFTune [[neftune]]
+
+[NEFTune](https://hf.co/papers/2310.05914)은 훈련 중 임베딩 벡터에 노이즈를 추가하여 성능을 향상시킬 수 있는 기술입니다. [`Trainer`]에서 이를 활성화하려면 [`TrainingArguments`]의 `neftune_noise_alpha` 매개변수를 설정하여 노이즈의 양을 조절합니다.
+
+```py
+from transformers import TrainingArguments, Trainer
+
+training_args = TrainingArguments(..., neftune_noise_alpha=0.1)
+trainer = Trainer(..., args=training_args)
+```
+
+NEFTune은 예상치 못한 동작을 피할 목적으로 처음 임베딩 레이어로 복원하기 위해 훈련 후 비활성화 됩니다.
+
+## GaLore [[galore]]
+
+Gradient Low-Rank Projection (GaLore)은 전체 매개변수를 학습하면서도 LoRA와 같은 일반적인 저계수 적응 방법보다 더 메모리 효율적인 저계수 학습 전략입니다.
+
+먼저 GaLore 공식 리포지토리를 설치합니다:
+
+```bash
+pip install galore-torch
+```
+
+그런 다음 `optim`에 `["galore_adamw", "galore_adafactor", "galore_adamw_8bit"]` 중 하나와 함께 `optim_target_modules`를 추가합니다. 이는 적용하려는 대상 모듈 이름에 해당하는 문자열, 정규 표현식 또는 전체 경로의 목록일 수 있습니다. 아래는 end-to-end 예제 스크립트입니다(필요한 경우 `pip install trl datasets`를 실행):
+
+```python
+import torch
+import datasets
+import trl
+
+from transformers import TrainingArguments, AutoConfig, AutoTokenizer, AutoModelForCausalLM
+
+train_dataset = datasets.load_dataset('imdb', split='train')
+
+args = TrainingArguments(
+ output_dir="./test-galore",
+ max_steps=100,
+ per_device_train_batch_size=2,
+ optim="galore_adamw",
+ optim_target_modules=["attn", "mlp"]
+)
+
+model_id = "google/gemma-2b"
+
+config = AutoConfig.from_pretrained(model_id)
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_config(config).to(0)
+
+trainer = trl.SFTTrainer(
+ model=model,
+ args=args,
+ train_dataset=train_dataset,
+ dataset_text_field='text',
+ max_seq_length=512,
+)
+
+trainer.train()
+```
+
+GaLore가 지원하는 추가 매개변수를 전달하려면 `optim_args`를 설정합니다. 예를 들어:
+
+```python
+import torch
+import datasets
+import trl
+
+from transformers import TrainingArguments, AutoConfig, AutoTokenizer, AutoModelForCausalLM
+
+train_dataset = datasets.load_dataset('imdb', split='train')
+
+args = TrainingArguments(
+ output_dir="./test-galore",
+ max_steps=100,
+ per_device_train_batch_size=2,
+ optim="galore_adamw",
+ optim_target_modules=["attn", "mlp"],
+ optim_args="rank=64, update_proj_gap=100, scale=0.10",
+)
+
+model_id = "google/gemma-2b"
+
+config = AutoConfig.from_pretrained(model_id)
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_config(config).to(0)
+
+trainer = trl.SFTTrainer(
+ model=model,
+ args=args,
+ train_dataset=train_dataset,
+ dataset_text_field='text',
+ max_seq_length=512,
+)
+
+trainer.train()
+```
+
+해당 방법에 대한 자세한 내용은 [원본 리포지토리](https://github.com/jiaweizzhao/GaLore) 또는 [논문](https://arxiv.org/abs/2403.03507)을 참고하세요.
+
+현재 GaLore 레이어로 간주되는 Linear 레이어만 훈련 할수 있으며, 저계수 분해를 사용하여 훈련되고 나머지 레이어는 기존 방식으로 최적화됩니다.
+
+훈련 시작 전에 시간이 약간 걸릴 수 있습니다(NVIDIA A100에서 2B 모델의 경우 약 3분), 하지만 이후 훈련은 원활하게 진행됩니다.
+
+다음과 같이 옵티마이저 이름에 `layerwise`를 추가하여 레이어별 최적화를 수행할 수도 있습니다:
+
+```python
+import torch
+import datasets
+import trl
+
+from transformers import TrainingArguments, AutoConfig, AutoTokenizer, AutoModelForCausalLM
+
+train_dataset = datasets.load_dataset('imdb', split='train')
+
+args = TrainingArguments(
+ output_dir="./test-galore",
+ max_steps=100,
+ per_device_train_batch_size=2,
+ optim="galore_adamw_layerwise",
+ optim_target_modules=["attn", "mlp"]
+)
+
+model_id = "google/gemma-2b"
+
+config = AutoConfig.from_pretrained(model_id)
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_config(config).to(0)
+
+trainer = trl.SFTTrainer(
+ model=model,
+ args=args,
+ train_dataset=train_dataset,
+ dataset_text_field='text',
+ max_seq_length=512,
+)
+
+trainer.train()
+```
+
+레이어별 최적화는 다소 실험적이며 DDP(분산 데이터 병렬)를 지원하지 않으므로, 단일 GPU에서만 훈련 스크립트를 실행할 수 있습니다. 자세한 내용은 [이 문서를](https://github.com/jiaweizzhao/GaLore?tab=readme-ov-file#train-7b-model-with-a-single-gpu-with-24gb-memory)을 참조하세요. gradient clipping, DeepSpeed 등 다른 기능은 기본적으로 지원되지 않을 수 있습니다. 이러한 문제가 발생하면 [GitHub에 이슈를 올려주세요](https://github.com/huggingface/transformers/issues).
+
+## LOMO 옵티마이저 [[lomo-optimizer]]
+
+LOMO 옵티마이저는 [제한된 자원으로 대형 언어 모델의 전체 매개변수 미세 조정](https://hf.co/papers/2306.09782)과 [적응형 학습률을 통한 저메모리 최적화(AdaLomo)](https://hf.co/papers/2310.10195)에서 도입되었습니다.
+이들은 모두 효율적인 전체 매개변수 미세 조정 방법으로 구성되어 있습니다. 이러한 옵티마이저들은 메모리 사용량을 줄이기 위해 그레이디언트 계산과 매개변수 업데이트를 하나의 단계로 융합합니다. LOMO에서 지원되는 옵티마이저는 `"lomo"`와 `"adalomo"`입니다. 먼저 pypi에서 `pip install lomo-optim`를 통해 `lomo`를 설치하거나, GitHub 소스에서 `pip install git+https://github.com/OpenLMLab/LOMO.git`로 설치하세요.
+
+
+
+저자에 따르면, `grad_norm` 없이 `AdaLomo`를 사용하는 것이 더 나은 성능과 높은 처리량을 제공한다고 합니다.
+
+
+
+다음은 IMDB 데이터셋에서 [google/gemma-2b](https://huggingface.co/google/gemma-2b)를 최대 정밀도로 미세 조정하는 간단한 스크립트입니다:
+
+```python
+import torch
+import datasets
+from transformers import TrainingArguments, AutoTokenizer, AutoModelForCausalLM
+import trl
+
+train_dataset = datasets.load_dataset('imdb', split='train')
+
+args = TrainingArguments(
+ output_dir="./test-lomo",
+ max_steps=1000,
+ per_device_train_batch_size=4,
+ optim="adalomo",
+ gradient_checkpointing=True,
+ logging_strategy="steps",
+ logging_steps=1,
+ learning_rate=2e-6,
+ save_strategy="no",
+ run_name="lomo-imdb",
+)
+
+model_id = "google/gemma-2b"
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id, low_cpu_mem_usage=True).to(0)
+
+trainer = trl.SFTTrainer(
+ model=model,
+ args=args,
+ train_dataset=train_dataset,
+ dataset_text_field='text',
+ max_seq_length=1024,
+)
+
+trainer.train()
+```
+
+## Accelerate와 Trainer [[accelerate-and-trainer]]
+
+[`Trainer`] 클래스는 [Accelerate](https://hf.co/docs/accelerate)로 구동되며, 이는 [FullyShardedDataParallel (FSDP)](https://pytorch.org/blog/introducing-pytorch-fully-sharded-data-parallel-api/) 및 [DeepSpeed](https://www.deepspeed.ai/)와 같은 통합을 지원하는 분산 환경에서 PyTorch 모델을 쉽게 훈련할 수 있는 라이브러리입니다.
+
+
+
+FSDP 샤딩 전략, CPU 오프로드 및 [`Trainer`]와 함께 사용할 수 있는 더 많은 기능을 알아보려면 [Fully Sharded Data Parallel](fsdp) 가이드를 확인하세요.
+
+
+
+[`Trainer`]와 Accelerate를 사용하려면 [`accelerate.config`](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-config) 명령을 실행하여 훈련 환경을 설정하세요. 이 명령은 훈련 스크립트를 실행할 때 사용할 `config_file.yaml`을 생성합니다. 예를 들어, 다음 예시는 설정할 수 있는 일부 구성 예입니다.
+
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+distributed_type: MULTI_GPU
+downcast_bf16: 'no'
+gpu_ids: all
+machine_rank: 0 # 노드에 따라 순위를 변경하세요
+main_process_ip: 192.168.20.1
+main_process_port: 9898
+main_training_function: main
+mixed_precision: fp16
+num_machines: 2
+num_processes: 8
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+distributed_type: FSDP
+downcast_bf16: 'no'
+fsdp_config:
+ fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
+ fsdp_backward_prefetch_policy: BACKWARD_PRE
+ fsdp_forward_prefetch: true
+ fsdp_offload_params: false
+ fsdp_sharding_strategy: 1
+ fsdp_state_dict_type: FULL_STATE_DICT
+ fsdp_sync_module_states: true
+ fsdp_transformer_layer_cls_to_wrap: BertLayer
+ fsdp_use_orig_params: true
+machine_rank: 0
+main_training_function: main
+mixed_precision: bf16
+num_machines: 1
+num_processes: 2
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+deepspeed_config:
+ deepspeed_config_file: /home/user/configs/ds_zero3_config.json
+ zero3_init_flag: true
+distributed_type: DEEPSPEED
+downcast_bf16: 'no'
+machine_rank: 0
+main_training_function: main
+num_machines: 1
+num_processes: 4
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+deepspeed_config:
+ gradient_accumulation_steps: 1
+ gradient_clipping: 0.7
+ offload_optimizer_device: cpu
+ offload_param_device: cpu
+ zero3_init_flag: true
+ zero_stage: 2
+distributed_type: DEEPSPEED
+downcast_bf16: 'no'
+machine_rank: 0
+main_training_function: main
+mixed_precision: bf16
+num_machines: 1
+num_processes: 4
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+
+
+
+[`accelerate_launch`](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-launch) 명령은 Accelerate와 [`Trainer`]를 사용하여 분산 시스템에서 훈련 스크립트를 실행하는 권장 방법이며, `config_file.yaml`에 지정된 매개변수를 사용합니다. 이 파일은 Accelerate 캐시 폴더에 저장되며 `accelerate_launch`를 실행할 때 자동으로 로드됩니다.
+
+예를 들어, FSDP 구성을 사용하여 [run_glue.py](https://github.com/huggingface/transformers/blob/f4db565b695582891e43a5e042e5d318e28f20b8/examples/pytorch/text-classification/run_glue.py#L4) 훈련 스크립트를 실행하려면 다음과 같이 합니다:
+
+```bash
+accelerate launch \
+ ./examples/pytorch/text-classification/run_glue.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --task_name $TASK_NAME \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 16 \
+ --learning_rate 5e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/ \
+ --overwrite_output_dir
+```
+
+`config_file.yaml` 파일의 매개변수를 직접 지정할 수도 있습니다:
+
+```bash
+accelerate launch --num_processes=2 \
+ --use_fsdp \
+ --mixed_precision=bf16 \
+ --fsdp_auto_wrap_policy=TRANSFORMER_BASED_WRAP \
+ --fsdp_transformer_layer_cls_to_wrap="BertLayer" \
+ --fsdp_sharding_strategy=1 \
+ --fsdp_state_dict_type=FULL_STATE_DICT \
+ ./examples/pytorch/text-classification/run_glue.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --task_name $TASK_NAME \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 16 \
+ --learning_rate 5e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/ \
+ --overwrite_output_dir
+```
+
+`accelerate_launch`와 사용자 정의 구성에 대해 더 알아보려면 [Accelerate 스크립트 실행](https://huggingface.co/docs/accelerate/basic_tutorials/launch) 튜토리얼을 확인하세요.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/training.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/training.md
new file mode 100644
index 0000000000000000000000000000000000000000..432ba186c3df0c36e298fee6fb0c939c6f206a6e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/training.md
@@ -0,0 +1,428 @@
+
+
+# 사전 학습된 모델 미세 튜닝하기[[finetune-a-pretrained-model]]
+
+[[open-in-colab]]
+
+사전 학습된 모델을 사용하면 상당한 이점이 있습니다. 계산 비용과 탄소발자국을 줄이고, 처음부터 모델을 학습시킬 필요 없이 최신 모델을 사용할 수 있습니다. 🤗 Transformers는 다양한 작업을 위해 사전 학습된 수천 개의 모델에 액세스할 수 있습니다. 사전 학습된 모델을 사용하는 경우, 자신의 작업과 관련된 데이터셋을 사용해 학습합니다. 이것은 미세 튜닝이라고 하는 매우 강력한 훈련 기법입니다. 이 튜토리얼에서는 당신이 선택한 딥러닝 프레임워크로 사전 학습된 모델을 미세 튜닝합니다:
+
+* 🤗 Transformers로 사전 학습된 모델 미세 튜닝하기 [`Trainer`].
+* Keras를 사용하여 TensorFlow에서 사전 학습된 모델을 미세 튜닝하기.
+* 기본 PyTorch에서 사전 학습된 모델을 미세 튜닝하기.
+
+
+
+
+
+사전 훈련된 가중치 중 일부가 사용되지 않고 일부 가중치가 무작위로 표시된다는 경고가 표시됩니다.
+걱정마세요. 이것은 올바른 동작입니다! 사전 학습된 BERT 모델의 헤드는 폐기되고 무작위로 초기화된 분류 헤드로 대체됩니다. 이제 사전 학습된 모델의 지식으로 시퀀스 분류 작업을 위한 새로운 모델 헤드를 미세 튜닝 합니다.
+
+
+
+### 하이퍼파라미터 훈련[[training-hyperparameters]]
+
+다음으로 정할 수 있는 모든 하이퍼파라미터와 다양한 훈련 옵션을 활성화하기 위한 플래그를 포함하는 [`TrainingArguments`] 클래스를 생성합니다.
+
+이 튜토리얼에서는 기본 훈련 [하이퍼파라미터](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments)로 시작하지만, 자유롭게 실험하여 여러분들에게 맞는 최적의 설정을 찾을 수 있습니다.
+
+훈련에서 체크포인트(checkpoints)를 저장할 위치를 지정합니다:
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(output_dir="test_trainer")
+```
+
+### 평가 하기[[evaluate]]
+
+[`Trainer`]는 훈련 중에 모델 성능을 자동으로 평가하지 않습니다. 평가 지표를 계산하고 보고할 함수를 [`Trainer`]에 전달해야 합니다.
+[🤗 Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리는 [`evaluate.load`](https://huggingface.co/spaces/evaluate-metric/accuracy) 함수로 로드할 수 있는 간단한 [`accuracy`]함수를 제공합니다 (자세한 내용은 [둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하세요):
+
+```py
+>>> import numpy as np
+>>> import evaluate
+
+>>> metric = evaluate.load("accuracy")
+```
+
+`metric`에서 [`~evaluate.compute`]를 호출하여 예측의 정확도를 계산합니다. 예측을 `compute`에 전달하기 전에 예측을 로짓으로 변환해야 합니다(모든 🤗 Transformers 모델은 로짓으로 반환한다는 점을 기억하세요):
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... predictions = np.argmax(logits, axis=-1)
+... return metric.compute(predictions=predictions, references=labels)
+```
+
+미세 튜닝 중에 평가 지표를 모니터링하려면 훈련 인수에 `eval_strategy` 파라미터를 지정하여 각 에폭이 끝날 때 평가 지표를 확인할 수 있습니다:
+
+```py
+>>> from transformers import TrainingArguments, Trainer
+
+>>> training_args = TrainingArguments(output_dir="test_trainer", eval_strategy="epoch")
+```
+
+### 훈련 하기[[trainer]]
+
+모델, 훈련 인수, 훈련 및 테스트 데이터셋, 평가 함수가 포함된 [`Trainer`] 객체를 만듭니다:
+
+```py
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=small_train_dataset,
+... eval_dataset=small_eval_dataset,
+... compute_metrics=compute_metrics,
+... )
+```
+
+그리고 [`~transformers.Trainer.train`]을 호출하여 모델을 미세 튜닝합니다:
+
+```py
+>>> trainer.train()
+```
+
+
+
+
+모델을 `compile()`할 때 손실 인수를 모델에 전달할 필요가 없습니다!
+이 인수를 비워두면 허깅 페이스 모델은 작업과 모델 아키텍처에 적합한 손실을 자동으로 선택합니다.
+원한다면 언제든지 직접 손실을 지정하여 이를 재정의할 수 있습니다!
+
+
+
+이 접근 방식은 소규모 데이터 집합에서는 잘 작동하지만, 대규모 데이터 집합에서는 문제가 될 수 있습니다. 왜 그럴까요?
+토큰화된 배열과 레이블을 메모리에 완전히 로드하고 NumPy는 "들쭉날쭉한" 배열을 처리하지 않기 때문에,
+모든 토큰화된 샘플을 전체 데이터셋에서 가장 긴 샘플의 길이만큼 패딩해야 합니다. 이렇게 하면 배열이 훨씬 더 커지고 이 패딩 토큰으로 인해 학습 속도도 느려집니다!
+
+### 데이터를 tf.data.Dataset으로 로드하기[[loading-data-as-a-tfdatadataset]]
+
+학습 속도가 느려지는 것을 피하려면 데이터를 `tf.data.Dataset`으로 로드할 수 있습니다. 원한다면 직접
+`tf.data` 파이프라인을 직접 작성할 수도 있지만, 이 작업을 간편하게 수행하는 수 있는 두 가지 방법이 있습니다:
+
+- [`~TFPreTrainedModel.prepare_tf_dataset`]: 대부분의 경우 이 방법을 권장합니다. 모델의 메서드이기 때문에 모델을 검사하여 모델 입력으로 사용할 수 있는 열을 자동으로 파악하고
+나머지는 버려서 더 단순하고 성능이 좋은 데이터 집합을 만들 수 있습니다.
+- [`~datasets.Dataset.to_tf_dataset`]: 이 방법은 좀 더 낮은 수준이며, 포함할 '열'과 '레이블'을 정확히 지정하여
+데이터셋을 생성하는 방법을 정확히 제어하고 싶을 때 유용하며, 포함할 'columns'과 'label_cols'을 정확히 지정할 수 있습니다.
+
+[`~TFPreTrainedModel.prepare_tf_dataset`]을 사용하려면 먼저 다음 코드 샘플과 같이 토크나이저 출력을 데이터 세트에 열로 추가해야 합니다:
+
+```py
+def tokenize_dataset(data):
+ # Keys of the returned dictionary will be added to the dataset as columns
+ return tokenizer(data["text"])
+
+
+dataset = dataset.map(tokenize_dataset)
+```
+
+허깅 페이스 데이터셋은 기본적으로 디스크에 저장되므로 메모리 사용량을 늘리지 않는다는 점을 기억하세요!
+열이 추가되면 데이터셋에서 배치를 스트리밍하고 각 배치에 패딩을 추가할 수 있으므로 전체 데이터셋에 패딩을 추가하는 것보다 패딩 토큰의 수를 크게 줄일 수 있습니다.
+
+
+```py
+>>> tf_dataset = model.prepare_tf_dataset(dataset, batch_size=16, shuffle=True, tokenizer=tokenizer)
+```
+
+위의 코드 샘플에서는 배치가 로드될 때 올바르게 패딩할 수 있도록 `prepare_tf_dataset`에 토크나이저를 전달해야 합니다.
+데이터셋의 모든 샘플 길이가 같고 패딩이 필요하지 않은 경우 이 인수를 건너뛸 수 있습니다.
+샘플을 채우는 것보다 더 복잡한 작업(예: 마스킹된 언어의 토큰 손상 모델링)을 수행하기 위해 토큰을 손상시켜야 하는 경우,
+`collate_fn` 인수를 사용하여 샘플 목록을 배치로 변환하고 원하는 전처리를 적용할 함수를 전달할 수 있습니다.
+[예시](https://github.com/huggingface/transformers/tree/main/examples) 또는
+[노트북](https://huggingface.co/docs/transformers/notebooks)을 참조하여 이 접근 방식이 실제로 작동하는 모습을 확인하세요.
+
+`tf.data.Dataset`을 생성한 후에는 이전과 마찬가지로 모델을 컴파일하고 훈련(fit)할 수 있습니다:
+
+```py
+model.compile(optimizer=Adam(3e-5))
+
+model.fit(tf_dataset)
+```
+
+
+
+
+
+
+
+
+[Colaboratory](https://colab.research.google.com/) 또는 [SageMaker StudioLab](https://studiolab.sagemaker.aws/)과 같은 호스팅 노트북이 없는 경우 클라우드 GPU에 무료로 액세스할 수 있습니다.
+
+
+
+이제 훈련할 준비가 되었습니다! 🥳
+
+### 훈련 루프[[training-loop]]
+
+훈련 진행 상황을 추적하려면 [tqdm](https://tqdm.github.io/) 라이브러리를 사용하여 트레이닝 단계 수에 진행률 표시줄을 추가하세요:
+
+```py
+>>> from tqdm.auto import tqdm
+
+>>> progress_bar = tqdm(range(num_training_steps))
+
+>>> model.train()
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... outputs = model(**batch)
+... loss = outputs.loss
+... loss.backward()
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+### 평가 하기[[evaluate]]
+
+[`Trainer`]에 평가 함수를 추가한 방법과 마찬가지로, 훈련 루프를 직접 작성할 때도 동일한 작업을 수행해야 합니다. 하지만 이번에는 각 에포크가 끝날 때마다 평가지표를 계산하여 보고하는 대신, [`~evaluate.add_batch`]를 사용하여 모든 배치를 누적하고 맨 마지막에 평가지표를 계산합니다.
+
+```py
+>>> import evaluate
+
+>>> metric = evaluate.load("accuracy")
+>>> model.eval()
+>>> for batch in eval_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... with torch.no_grad():
+... outputs = model(**batch)
+
+... logits = outputs.logits
+... predictions = torch.argmax(logits, dim=-1)
+... metric.add_batch(predictions=predictions, references=batch["labels"])
+
+>>> metric.compute()
+```
+
+
+
+
+
+Transformers Agent는 실험 중인 API로 언제든지 변경될 수 있습니다.
+API 또는 기반 모델이 변경되기 쉽기 때문에 에이전트가 반환하는 결과도 달라질 수 있습니다.
+
+
+
+Transformers 버전 4.29.0.에서 *도구*와 *에이전트*라는 컨셉을 도입했습니다. [이 colab](https://colab.research.google.com/drive/1c7MHD-T1forUPGcC_jlwsIptOzpG3hSj)에서 사용해볼 수 있습니다.
+
+간단히 말하면, Agent는 트랜스포머 위에 자연어 API를 제공합니다.
+엄선된 도구 세트를 정의하고, 자연어를 해석하여 이러한 도구를 사용할 수 있는 에이전트를 설계했습니다.
+이 API는 확장이 가능하도록 설계 되었습니다.
+주요 도구를 선별해두었지만, 커뮤니티에서 개발한 모든 도구를 사용할 수 있도록 시스템을 쉽게 확장할 수 있는 방법도 보여드리겠습니다.
+
+몇 가지 예를 통해 새로운 API로 무엇을 할 수 있는지 살펴보겠습니다.
+이 API는 특히 멀티모달 작업에서 강력하므로 이미지를 생성하고 텍스트를 소리내어 읽어보겠습니다.
+
+```py
+agent.run("Caption the following image", image=image)
+```
+
+| **Input** | **Output** |
+|-----------------------------------------------------------------------------------------------------------------------------|-----------------------------------|
+| your browser does not support the audio element. ")
+```
+
+BigCode 또는 OpenAssistant를 사용하려면 먼저 로그인하여 Inference API에 액세스하세요:
+
+```py
+from huggingface_hub import login
+
+login("")
+```
+
+그런 다음 에이전트를 인스턴스화합니다.
+
+```py
+from transformers import HfAgent
+
+# Starcoder
+agent = HfAgent("https://api-inference.huggingface.co/models/bigcode/starcoder")
+# StarcoderBase
+# agent = HfAgent("https://api-inference.huggingface.co/models/bigcode/starcoderbase")
+# OpenAssistant
+# agent = HfAgent(url_endpoint="https://api-inference.huggingface.co/models/OpenAssistant/oasst-sft-4-pythia-12b-epoch-3.5")
+```
+
+현재 Hugging Face에서 무료로 제공하는 추론 API를 사용하고 있습니다.
+이 모델에 대한 자체 추론 엔드포인트가 있는 경우(또는 다른 엔드포인트가 있는 경우) 위의 URL을 해당 URL 엔드포인트로 바꿀 수 있습니다.
+
+
+
+StarCoder와 OpenAssistant는 무료로 사용할 수 있으며 간단한 작업에서 놀라울 정도로 잘 작동합니다.
+그러나 더 복잡한 프롬프트를 처리할 때는 체크포인트가 잘 작동하지 않습니다.
+이러한 문제가 발생하면 OpenAI 모델을 사용해 보시기 바랍니다. 아쉽게도 오픈소스는 아니지만 현재로서는 더 나은 성능을 제공합니다.
+
+
+
+이제 준비가 완료되었습니다! 이제 자유롭게 사용할 수 있는 두 가지 API에 대해 자세히 알아보겠습니다.
+
+### 단일 실행 (run) [[single-execution-(run)]]
+
+단일 실행 방법은 에이전트의 [`~Agent.run`] 메소드를 사용하는 경우입니다:
+
+```py
+agent.run("Draw me a picture of rivers and lakes.")
+```
+
+
+
+이 방법은 모델이 요청을 이해하지 못하고 도구를 혼합할 때 유용할 수 있습니다. 예를 들면 다음과 같습니다:
+
+```py
+agent.run("Draw me the picture of a capybara swimming in the sea")
+```
+
+여기서 모델은 두 가지 방식으로 해석할 수 있습니다:
+- `text-to-image`이 바다에서 헤엄치는 카피바라를 생성하도록 합니다.
+- 또는 `text-to-image`이 카피바라를 생성한 다음 `image-transformation` 도구를 사용하여 바다에서 헤엄치도록 합니다.
+
+첫 번째 시나리오를 강제로 실행하려면 프롬프트를 인수로 전달하여 실행할 수 있습니다:
+
+```py
+agent.run("Draw me a picture of the `prompt`", prompt="a capybara swimming in the sea")
+```
+
+
+
+
+### 대화 기반 실행 (chat) [[chat-based-execution-(chat)]]
+
+에이전트는 [`~Agent.chat`] 메소드를 사용하는 대화 기반 접근 방식도 있습니다:
+
+```py
+agent.chat("Generate a picture of rivers and lakes")
+```
+
+
+
+메모리 절약 기술에 대한 자세한 내용은 성능 [가이드](performance)를 참조하세요.
+
+
+
+## 저장된 TensorFlow 모델을 가져올 수 없습니다(Unable to load a saved TensorFlow model)[[unable-to-load-a-saved-uensorFlow-model]]
+
+TensorFlow의 [model.save](https://www.tensorflow.org/tutorials/keras/save_and_load#save_the_entire_model) 메소드는 아키텍처, 가중치, 훈련 구성 등 전체 모델을 단일 파일에 저장합니다. 그러나 모델 파일을 다시 가져올 때 🤗 Transformers는 모델 파일에 있는 모든 TensorFlow 관련 객체를 가져오지 않을 수 있기 때문에 오류가 발생할 수 있습니다. TensorFlow 모델 저장 및 가져오기 문제를 피하려면 다음을 권장합니다:
+
+- 모델 가중치를 `h5` 파일 확장자로 [`model.save_weights`](https://www.tensorflow.org/tutorials/keras/save_and_load#save_the_entire_model)로 저장한 다음 [`~TFPreTrainedModel.from_pretrained`]로 모델을 다시 가져옵니다:
+
+```py
+>>> from transformers import TFPreTrainedModel
+>>> from tensorflow import keras
+
+>>> model.save_weights("some_folder/tf_model.h5")
+>>> model = TFPreTrainedModel.from_pretrained("some_folder")
+```
+
+- 모델을 [`~TFPretrainedModel.save_pretrained`]로 저장하고 [`~TFPreTrainedModel.from_pretrained`]로 다시 가져옵니다:
+
+```py
+>>> from transformers import TFPreTrainedModel
+
+>>> model.save_pretrained("path_to/model")
+>>> model = TFPreTrainedModel.from_pretrained("path_to/model")
+```
+
+## ImportError[[importerror]]
+
+특히 최신 모델인 경우 만날 수 있는 다른 일반적인 오류는 `ImportError`입니다:
+
+```
+ImportError: cannot import name 'ImageGPTImageProcessor' from 'transformers' (unknown location)
+```
+
+이러한 오류 유형의 경우 최신 모델에 액세스할 수 있도록 최신 버전의 🤗 Transformers가 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers --upgrade
+```
+
+## CUDA error: device-side assert triggered[[cuda-error-deviceside-assert-triggered]]
+
+때때로 장치 코드 오류에 대한 일반적인 CUDA 오류가 발생할 수 있습니다.
+
+```
+RuntimeError: CUDA error: device-side assert triggered
+```
+
+더 자세한 오류 메시지를 얻으려면 우선 코드를 CPU에서 실행합니다. 다음 환경 변수를 코드의 시작 부분에 추가하여 CPU로 전환하세요:
+
+```py
+>>> import os
+
+>>> os.environ["CUDA_VISIBLE_DEVICES"] = ""
+```
+
+또 다른 옵션은 GPU에서 더 나은 역추적(traceback)을 얻는 것입니다. 다음 환경 변수를 코드의 시작 부분에 추가하여 역추적이 오류가 발생한 소스를 가리키도록 하세요:
+
+```py
+>>> import os
+
+>>> os.environ["CUDA_LAUNCH_BLOCKING"] = "1"
+```
+
+## 패딩 토큰이 마스킹되지 않은 경우 잘못된 출력(Incorrect output when padding tokens aren't masked)[[incorrect-output-when-padding-tokens-arent-masked]]
+
+경우에 따라 `input_ids`에 패딩 토큰이 포함된 경우 `hidden_state` 출력이 올바르지 않을 수 있습니다. 데모를 위해 모델과 토크나이저를 가져오세요. 모델의 `pad_token_id`에 액세스하여 해당 값을 확인할 수 있습니다. 일부 모델의 경우 `pad_token_id`가 `None`일 수 있지만 언제든지 수동으로 설정할 수 있습니다.
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+>>> import torch
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-uncased")
+>>> model.config.pad_token_id
+0
+```
+
+다음 예제는 패딩 토큰을 마스킹하지 않은 출력을 보여줍니다:
+
+```py
+>>> input_ids = torch.tensor([[7592, 2057, 2097, 2393, 9611, 2115], [7592, 0, 0, 0, 0, 0]])
+>>> output = model(input_ids)
+>>> print(output.logits)
+tensor([[ 0.0082, -0.2307],
+ [ 0.1317, -0.1683]], grad_fn=)
+```
+
+다음은 두 번째 시퀀스의 실제 출력입니다:
+
+```py
+>>> input_ids = torch.tensor([[7592]])
+>>> output = model(input_ids)
+>>> print(output.logits)
+tensor([[-0.1008, -0.4061]], grad_fn=)
+```
+
+대부분의 경우 모델에 `attention_mask`를 제공하여 패딩 토큰을 무시해야 이러한 조용한 오류를 방지할 수 있습니다. 이제 두 번째 시퀀스의 출력이 실제 출력과 일치합니다:
+
+
+
+일반적으로 토크나이저는 특정 토크나이저의 기본 값을 기준으로 사용자에 대한 'attention_mask'를 만듭니다.
+
+
+
+```py
+>>> attention_mask = torch.tensor([[1, 1, 1, 1, 1, 1], [1, 0, 0, 0, 0, 0]])
+>>> output = model(input_ids, attention_mask=attention_mask)
+>>> print(output.logits)
+tensor([[ 0.0082, -0.2307],
+ [-0.1008, -0.4061]], grad_fn=)
+```
+
+🤗 Transformers는 패딩 토큰이 제공된 경우 패딩 토큰을 마스킹하기 위한 `attention_mask`를 자동으로 생성하지 않습니다. 그 이유는 다음과 같습니다:
+
+- 일부 모델에는 패딩 토큰이 없습니다.
+- 일부 사용 사례의 경우 사용자가 모델이 패딩 토큰을 관리하기를 원합니다.
+
+## ValueError: 이 유형의 AutoModel에 대해 인식할 수 없는 XYZ 구성 클래스(ValueError: Unrecognized configuration class XYZ for this kind of AutoModel)[[valueerror-unrecognized-configuration-class-xyz-for-this-kind-of-automodel]]
+
+일반적으로, 사전 학습된 모델의 인스턴스를 가져오기 위해 [`AutoModel`] 클래스를 사용하는 것이 좋습니다.
+이 클래스는 구성에 따라 주어진 체크포인트에서 올바른 아키텍처를 자동으로 추론하고 가져올 수 있습니다.
+모델을 체크포인트에서 가져올 때 이 `ValueError`가 발생하면, 이는 Auto 클래스가 주어진 체크포인트의 구성에서
+가져오려는 모델 유형과 매핑을 찾을 수 없다는 것을 의미합니다. 가장 흔하게 발생하는 경우는
+체크포인트가 주어진 태스크를 지원하지 않을 때입니다.
+예를 들어, 다음 예제에서 질의응답에 대한 GPT2가 없기 때문에 오류가 발생합니다:
+
+```py
+>>> from transformers import AutoProcessor, AutoModelForQuestionAnswering
+
+>>> processor = AutoProcessor.from_pretrained("openai-community/gpt2-medium")
+>>> model = AutoModelForQuestionAnswering.from_pretrained("openai-community/gpt2-medium")
+ValueError: Unrecognized configuration class for this kind of AutoModel: AutoModelForQuestionAnswering.
+Model type should be one of AlbertConfig, BartConfig, BertConfig, BigBirdConfig, BigBirdPegasusConfig, BloomConfig, ...
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ms/_toctree.yml b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ms/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..d69f13511e1023486765cf2450ed3e8154f2e08a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ms/_toctree.yml
@@ -0,0 +1,686 @@
+- sections:
+ - local: index
+ title: 🤗 Transformers
+ - local: quicktour
+ title: Lawatan cepat
+ - local: installation
+ title: Pemasangan
+ title: Mulakan
+- sections:
+ - local: pipeline_tutorial
+ title: Jalankan inferens dengan saluran paip
+ - local: autoclass_tutorial
+ title: Tulis kod mudah alih dengan AutoClass
+ - local: preprocessing
+ title: Praproses data
+ - local: training
+ title: Perhalusi model yang telah dilatih
+ - local: run_scripts
+ title: Latih dengan skrip
+ - local: accelerate
+ title: Sediakan latihan yang diedarkan dengan 🤗 Accelerate
+ - local: model_sharing
+ title: Kongsi model anda
+ - local: transformers_agents
+ title: Ejen
+ title: Tutorials
+- sections:
+ - sections:
+ - local: tasks/sequence_classification
+ title: Klasifikasi teks
+ - local: tasks/token_classification
+ title: Klasifikasi token
+ - local: tasks/question_answering
+ title: Soalan menjawab
+ - local: tasks/language_modeling
+ title: Pemodelan bahasa sebab-akibat
+ - local: tasks/masked_language_modeling
+ title: Pemodelan bahasa Masked
+ - local: tasks/translation
+ title: Terjemahan
+ - local: tasks/summarization
+ title: Rumusan
+ - local: tasks/multiple_choice
+ title: Pilihan
+ title: Natural Language Processing
+ isExpanded: false
+ - sections:
+ - local: tasks/audio_classification
+ title: Klasifikasi audio
+ - local: tasks/asr
+ title: Pengecaman pertuturan automatik
+ title: Audio
+ isExpanded: false
+ - sections:
+ - local: tasks/image_classification
+ title: Klasifikasi imej
+ - local: tasks/semantic_segmentation
+ title: Segmentasi semantik
+ - local: tasks/video_classification
+ title: Klasifikasi video
+ - local: tasks/object_detection
+ title: Pengesanan objek
+ - local: tasks/zero_shot_object_detection
+ title: Pengesanan objek Zero-Shot
+ - local: tasks/zero_shot_image_classification
+ title: Klasifikasi imej tangkapan Zero-Shot
+ - local: tasks/monocular_depth_estimation
+ title: Anggaran kedalaman
+ title: Visi komputer
+ isExpanded: false
+ - sections:
+ - local: tasks/image_captioning
+ title: Kapsyen imej
+ - local: tasks/document_question_answering
+ title: Menjawab Soalan Dokumen
+ - local: tasks/text-to-speech
+ title: Teks kepada ucapan
+ title: Multimodal
+ isExpanded: false
+ title: Panduan Tugasan
+- sections:
+ - local: fast_tokenizers
+ title: Gunakan tokenizer cepat dari 🤗 Tokenizers
+ - local: multilingual
+ title: Jalankan inferens dengan model berbilang bahasa
+ - local: generation_strategies
+ title: Sesuaikan strategi penjanaan teks
+ - local: create_a_model
+ title: Gunakan API khusus model
+ - local: custom_models
+ title: Kongsi model tersuai
+ - local: sagemaker
+ title: Jalankan latihan di Amazon SageMaker
+ - local: serialization
+ title: Eksport ke ONNX
+ - local: torchscript
+ title: Eksport ke TorchScript
+ - local: benchmarks
+ title: Penanda aras
+ - local: Buku nota dengan contoh
+ title: Notebooks with examples
+ - local: Sumber komuniti
+ title: Community resources
+ - local: Sumber komuniti
+ title: Custom Tools and Prompts
+ - local: Alat dan Gesaan Tersuai
+ title: Selesaikan masalah
+ title: Panduan Developer
+- sections:
+ - local: performance
+ title: Gambaran keseluruhan
+ - local: perf_train_gpu_one
+ title: Latihan pada satu GPU
+ - local: perf_train_gpu_many
+ title: Latihan pada banyak GPU
+ - local: perf_train_cpu
+ title: Latihan mengenai CPU
+ - local: perf_train_cpu_many
+ title: Latihan pada banyak CPU
+ - local: perf_train_tpu
+ title: Latihan mengenai TPU
+ - local: perf_train_tpu_tf
+ title: Latihan tentang TPU dengan TensorFlow
+ - local: perf_train_special
+ title: Latihan mengenai Perkakasan Khusus
+ - local: perf_infer_cpu
+ title: Inferens pada CPU
+ - local: perf_infer_gpu_one
+ title: Inferens pada satu GPU
+ - local: perf_infer_gpu_many
+ title: Inferens pada banyak GPUs
+ - local: perf_infer_special
+ title: Inferens pada Perkakasan Khusus
+ - local: perf_hardware
+ title: Perkakasan tersuai untuk latihan
+ - local: big_models
+ title: Menghidupkan model besar
+ - local: debugging
+ title: Penyahpepijatan
+ - local: hpo_train
+ title: Carian Hiperparameter menggunakan API Pelatih
+ - local: tf_xla
+ title: Penyepaduan XLA untuk Model TensorFlow
+ title: Prestasi dan kebolehskalaan
+- sections:
+ - local: contributing
+ title: Bagaimana untuk menyumbang kepada transformer?
+ - local: add_new_model
+ title: Bagaimana untuk menambah model pada 🤗 Transformers?
+ - local: add_new_pipeline
+ title: Bagaimana untuk menambah saluran paip ke 🤗 Transformers?
+ - local: testing
+ title: Ujian
+ - local: pr_checks
+ title: Menyemak Permintaan Tarik
+ title: Sumbangkan
+
+- sections:
+ - local: philosophy
+ title: Falsafah
+ - local: glossary
+ title: Glosari
+ - local: task_summary
+ title: Apa 🤗 Transformers boleh buat
+ - local: tasks_explained
+ title: Bagaimana 🤗 Transformers menyelesaikan tugasan
+ - local: model_summary
+ title: Keluarga model Transformer
+ - local: tokenizer_summary
+ title: Ringkasan tokenizer
+ - local: attention
+ title: Mekanisme perhatian
+ - local: pad_truncation
+ title: Padding dan pemotongan
+ - local: bertology
+ title: BERTology
+ - local: perplexity
+ title: Kekeliruan model panjang tetap
+ - local: pipeline_webserver
+ title: Saluran paip untuk inferens pelayan web
+ title: Panduan konsep
+- sections:
+ - sections:
+ - local: main_classes/agent
+ title: Ejen dan Alat
+ - local: model_doc/auto
+ title: Kelas Auto
+ - local: main_classes/callback
+ title: Panggilan balik
+ - local: main_classes/configuration
+ title: Configuration
+ - local: main_classes/data_collator
+ title: Data Collator
+ - local: main_classes/keras_callbacks
+ title: Keras callbacks
+ - local: main_classes/logging
+ title: Logging
+ - local: main_classes/model
+ title: Models
+ - local: main_classes/text_generation
+ title: Text Generation
+ - local: main_classes/onnx
+ title: ONNX
+ - local: main_classes/optimizer_schedules
+ title: Optimization
+ - local: main_classes/output
+ title: Model outputs
+ - local: main_classes/pipelines
+ title: Pipelines
+ - local: main_classes/processors
+ title: Processors
+ - local: main_classes/quantization
+ title: Quantization
+ - local: main_classes/tokenizer
+ title: Tokenizer
+ - local: main_classes/trainer
+ title: Trainer
+ - local: main_classes/deepspeed
+ title: DeepSpeed Integration
+ - local: main_classes/feature_extractor
+ title: Feature Extractor
+ - local: main_classes/image_processor
+ title: Image Processor
+ title: Main Classes
+ - sections:
+ - isExpanded: false
+ sections:
+ - local: model_doc/albert
+ title: ALBERT
+ - local: model_doc/bart
+ title: BART
+ - local: model_doc/barthez
+ title: BARThez
+ - local: model_doc/bartpho
+ title: BARTpho
+ - local: model_doc/bert
+ title: BERT
+ - local: model_doc/bert-generation
+ title: BertGeneration
+ - local: model_doc/bert-japanese
+ title: BertJapanese
+ - local: model_doc/bertweet
+ title: Bertweet
+ - local: model_doc/big_bird
+ title: BigBird
+ - local: model_doc/bigbird_pegasus
+ title: BigBirdPegasus
+ - local: model_doc/biogpt
+ title: BioGpt
+ - local: model_doc/blenderbot
+ title: Blenderbot
+ - local: model_doc/blenderbot-small
+ title: Blenderbot Small
+ - local: model_doc/bloom
+ title: BLOOM
+ - local: model_doc/bort
+ title: BORT
+ - local: model_doc/byt5
+ title: ByT5
+ - local: model_doc/camembert
+ title: CamemBERT
+ - local: model_doc/canine
+ title: CANINE
+ - local: model_doc/codegen
+ title: CodeGen
+ - local: model_doc/convbert
+ title: ConvBERT
+ - local: model_doc/cpm
+ title: CPM
+ - local: model_doc/cpmant
+ title: CPMANT
+ - local: model_doc/ctrl
+ title: CTRL
+ - local: model_doc/deberta
+ title: DeBERTa
+ - local: model_doc/deberta-v2
+ title: DeBERTa-v2
+ - local: model_doc/dialogpt
+ title: DialoGPT
+ - local: model_doc/distilbert
+ title: DistilBERT
+ - local: model_doc/dpr
+ title: DPR
+ - local: model_doc/electra
+ title: ELECTRA
+ - local: model_doc/encoder-decoder
+ title: Encoder Decoder Models
+ - local: model_doc/ernie
+ title: ERNIE
+ - local: model_doc/ernie_m
+ title: ErnieM
+ - local: model_doc/esm
+ title: ESM
+ - local: model_doc/flan-t5
+ title: FLAN-T5
+ - local: model_doc/flan-ul2
+ title: FLAN-UL2
+ - local: model_doc/flaubert
+ title: FlauBERT
+ - local: model_doc/fnet
+ title: FNet
+ - local: model_doc/fsmt
+ title: FSMT
+ - local: model_doc/funnel
+ title: Funnel Transformer
+ - local: model_doc/openai-gpt
+ title: GPT
+ - local: model_doc/gpt_neo
+ title: GPT Neo
+ - local: model_doc/gpt_neox
+ title: GPT NeoX
+ - local: model_doc/gpt_neox_japanese
+ title: GPT NeoX Japanese
+ - local: model_doc/gptj
+ title: GPT-J
+ - local: model_doc/gpt2
+ title: GPT2
+ - local: model_doc/gpt_bigcode
+ title: GPTBigCode
+ - local: model_doc/gptsan-japanese
+ title: GPTSAN Japanese
+ - local: model_doc/gpt-sw3
+ title: GPTSw3
+ - local: model_doc/herbert
+ title: HerBERT
+ - local: model_doc/ibert
+ title: I-BERT
+ - local: model_doc/jukebox
+ title: Jukebox
+ - local: model_doc/led
+ title: LED
+ - local: model_doc/llama
+ title: LLaMA
+ - local: model_doc/longformer
+ title: Longformer
+ - local: model_doc/longt5
+ title: LongT5
+ - local: model_doc/luke
+ title: LUKE
+ - local: model_doc/m2m_100
+ title: M2M100
+ - local: model_doc/marian
+ title: MarianMT
+ - local: model_doc/markuplm
+ title: MarkupLM
+ - local: model_doc/mbart
+ title: MBart and MBart-50
+ - local: model_doc/mega
+ title: MEGA
+ - local: model_doc/megatron-bert
+ title: MegatronBERT
+ - local: model_doc/megatron_gpt2
+ title: MegatronGPT2
+ - local: model_doc/mluke
+ title: mLUKE
+ - local: model_doc/mobilebert
+ title: MobileBERT
+ - local: model_doc/mpnet
+ title: MPNet
+ - local: model_doc/mt5
+ title: MT5
+ - local: model_doc/mvp
+ title: MVP
+ - local: model_doc/nezha
+ title: NEZHA
+ - local: model_doc/nllb
+ title: NLLB
+ - local: model_doc/nllb-moe
+ title: NLLB-MoE
+ - local: model_doc/nystromformer
+ title: Nyströmformer
+ - local: model_doc/open-llama
+ title: Open-Llama
+ - local: model_doc/opt
+ title: OPT
+ - local: model_doc/pegasus
+ title: Pegasus
+ - local: model_doc/pegasus_x
+ title: PEGASUS-X
+ - local: model_doc/phobert
+ title: PhoBERT
+ - local: model_doc/plbart
+ title: PLBart
+ - local: model_doc/prophetnet
+ title: ProphetNet
+ - local: model_doc/qdqbert
+ title: QDQBert
+ - local: model_doc/rag
+ title: RAG
+ - local: model_doc/realm
+ title: REALM
+ - local: model_doc/reformer
+ title: Reformer
+ - local: model_doc/rembert
+ title: RemBERT
+ - local: model_doc/retribert
+ title: RetriBERT
+ - local: model_doc/roberta
+ title: RoBERTa
+ - local: model_doc/roberta-prelayernorm
+ title: RoBERTa-PreLayerNorm
+ - local: model_doc/roc_bert
+ title: RoCBert
+ - local: model_doc/roformer
+ title: RoFormer
+ - local: model_doc/rwkv
+ title: RWKV
+ - local: model_doc/splinter
+ title: Splinter
+ - local: model_doc/squeezebert
+ title: SqueezeBERT
+ - local: model_doc/switch_transformers
+ title: SwitchTransformers
+ - local: model_doc/t5
+ title: T5
+ - local: model_doc/t5v1.1
+ title: T5v1.1
+ - local: model_doc/tapex
+ title: TAPEX
+ - local: model_doc/transfo-xl
+ title: Transformer XL
+ - local: model_doc/ul2
+ title: UL2
+ - local: model_doc/xmod
+ title: X-MOD
+ - local: model_doc/xglm
+ title: XGLM
+ - local: model_doc/xlm
+ title: XLM
+ - local: model_doc/xlm-prophetnet
+ title: XLM-ProphetNet
+ - local: model_doc/xlm-roberta
+ title: XLM-RoBERTa
+ - local: model_doc/xlm-roberta-xl
+ title: XLM-RoBERTa-XL
+ - local: model_doc/xlm-v
+ title: XLM-V
+ - local: model_doc/xlnet
+ title: XLNet
+ - local: model_doc/yoso
+ title: YOSO
+ title: Text models
+ - isExpanded: false
+ sections:
+ - local: model_doc/beit
+ title: BEiT
+ - local: model_doc/bit
+ title: BiT
+ - local: model_doc/conditional_detr
+ title: Conditional DETR
+ - local: model_doc/convnext
+ title: ConvNeXT
+ - local: model_doc/convnextv2
+ title: ConvNeXTV2
+ - local: model_doc/cvt
+ title: CvT
+ - local: model_doc/deformable_detr
+ title: Deformable DETR
+ - local: model_doc/deit
+ title: DeiT
+ - local: model_doc/deta
+ title: DETA
+ - local: model_doc/detr
+ title: DETR
+ - local: model_doc/dinat
+ title: DiNAT
+ - local: model_doc/dit
+ title: DiT
+ - local: model_doc/dpt
+ title: DPT
+ - local: model_doc/efficientformer
+ title: EfficientFormer
+ - local: model_doc/efficientnet
+ title: EfficientNet
+ - local: model_doc/focalnet
+ title: FocalNet
+ - local: model_doc/glpn
+ title: GLPN
+ - local: model_doc/imagegpt
+ title: ImageGPT
+ - local: model_doc/levit
+ title: LeViT
+ - local: model_doc/mask2former
+ title: Mask2Former
+ - local: model_doc/maskformer
+ title: MaskFormer
+ - local: model_doc/mobilenet_v1
+ title: MobileNetV1
+ - local: model_doc/mobilenet_v2
+ title: MobileNetV2
+ - local: model_doc/mobilevit
+ title: MobileViT
+ - local: model_doc/nat
+ title: NAT
+ - local: model_doc/poolformer
+ title: PoolFormer
+ - local: model_doc/regnet
+ title: RegNet
+ - local: model_doc/resnet
+ title: ResNet
+ - local: model_doc/segformer
+ title: SegFormer
+ - local: model_doc/swiftformer
+ title: SwiftFormer
+ - local: model_doc/swin
+ title: Swin Transformer
+ - local: model_doc/swinv2
+ title: Swin Transformer V2
+ - local: model_doc/swin2sr
+ title: Swin2SR
+ - local: model_doc/table-transformer
+ title: Table Transformer
+ - local: model_doc/timesformer
+ title: TimeSformer
+ - local: model_doc/upernet
+ title: UperNet
+ - local: model_doc/van
+ title: VAN
+ - local: model_doc/videomae
+ title: VideoMAE
+ - local: model_doc/vit
+ title: Vision Transformer (ViT)
+ - local: model_doc/vit_hybrid
+ title: ViT Hybrid
+ - local: model_doc/vit_mae
+ title: ViTMAE
+ - local: model_doc/vit_msn
+ title: ViTMSN
+ - local: model_doc/yolos
+ title: YOLOS
+ title: Vision models
+ - isExpanded: false
+ sections:
+ - local: model_doc/audio-spectrogram-transformer
+ title: Audio Spectrogram Transformer
+ - local: model_doc/clap
+ title: CLAP
+ - local: model_doc/hubert
+ title: Hubert
+ - local: model_doc/mctct
+ title: MCTCT
+ - local: model_doc/sew
+ title: SEW
+ - local: model_doc/sew-d
+ title: SEW-D
+ - local: model_doc/speech_to_text
+ title: Speech2Text
+ - local: model_doc/speech_to_text_2
+ title: Speech2Text2
+ - local: model_doc/speecht5
+ title: SpeechT5
+ - local: model_doc/unispeech
+ title: UniSpeech
+ - local: model_doc/unispeech-sat
+ title: UniSpeech-SAT
+ - local: model_doc/wav2vec2
+ title: Wav2Vec2
+ - local: model_doc/wav2vec2-conformer
+ title: Wav2Vec2-Conformer
+ - local: model_doc/wav2vec2_phoneme
+ title: Wav2Vec2Phoneme
+ - local: model_doc/wavlm
+ title: WavLM
+ - local: model_doc/whisper
+ title: Whisper
+ - local: model_doc/xls_r
+ title: XLS-R
+ - local: model_doc/xlsr_wav2vec2
+ title: XLSR-Wav2Vec2
+ title: Audio models
+ - isExpanded: false
+ sections:
+ - local: model_doc/align
+ title: ALIGN
+ - local: model_doc/altclip
+ title: AltCLIP
+ - local: model_doc/blip
+ title: BLIP
+ - local: model_doc/blip-2
+ title: BLIP-2
+ - local: model_doc/bridgetower
+ title: BridgeTower
+ - local: model_doc/chinese_clip
+ title: Chinese-CLIP
+ - local: model_doc/clip
+ title: CLIP
+ - local: model_doc/clipseg
+ title: CLIPSeg
+ - local: model_doc/data2vec
+ title: Data2Vec
+ - local: model_doc/deplot
+ title: DePlot
+ - local: model_doc/donut
+ title: Donut
+ - local: model_doc/flava
+ title: FLAVA
+ - local: model_doc/git
+ title: GIT
+ - local: model_doc/groupvit
+ title: GroupViT
+ - local: model_doc/layoutlm
+ title: LayoutLM
+ - local: model_doc/layoutlmv2
+ title: LayoutLMV2
+ - local: model_doc/layoutlmv3
+ title: LayoutLMV3
+ - local: model_doc/layoutxlm
+ title: LayoutXLM
+ - local: model_doc/lilt
+ title: LiLT
+ - local: model_doc/lxmert
+ title: LXMERT
+ - local: model_doc/matcha
+ title: MatCha
+ - local: model_doc/mgp-str
+ title: MGP-STR
+ - local: model_doc/oneformer
+ title: OneFormer
+ - local: model_doc/owlvit
+ title: OWL-ViT
+ - local: model_doc/perceiver
+ title: Perceiver
+ - local: model_doc/pix2struct
+ title: Pix2Struct
+ - local: model_doc/sam
+ title: Segment Anything
+ - local: model_doc/speech-encoder-decoder
+ title: Speech Encoder Decoder Models
+ - local: model_doc/tapas
+ title: TAPAS
+ - local: model_doc/trocr
+ title: TrOCR
+ - local: model_doc/tvlt
+ title: TVLT
+ - local: model_doc/vilt
+ title: ViLT
+ - local: model_doc/vision-encoder-decoder
+ title: Vision Encoder Decoder Models
+ - local: model_doc/vision-text-dual-encoder
+ title: Vision Text Dual Encoder
+ - local: model_doc/visual_bert
+ title: VisualBERT
+ - local: model_doc/xclip
+ title: X-CLIP
+ title: Multimodal models
+ - isExpanded: false
+ sections:
+ - local: model_doc/decision_transformer
+ title: Decision Transformer
+ - local: model_doc/trajectory_transformer
+ title: Trajectory Transformer
+ title: Reinforcement learning models
+ - isExpanded: false
+ sections:
+ - local: model_doc/informer
+ title: Informer
+ - local: model_doc/time_series_transformer
+ title: Time Series Transformer
+ title: Time series models
+ - isExpanded: false
+ sections:
+ - local: model_doc/graphormer
+ title: Graphormer
+ title: Graph models
+ title: Models
+ - sections:
+ - local: internal/modeling_utils
+ title: Custom Layers and Utilities
+ - local: internal/pipelines_utils
+ title: Utilities for pipelines
+ - local: internal/tokenization_utils
+ title: Utilities for Tokenizers
+ - local: internal/trainer_utils
+ title: Utilities for Trainer
+ - local: internal/generation_utils
+ title: Utilities for Generation
+ - local: internal/image_processing_utils
+ title: Utilities for Image Processors
+ - local: internal/audio_utils
+ title: Utilities for Audio processing
+ - local: internal/file_utils
+ title: General Utilities
+ - local: internal/time_series_utils
+ title: Utilities for Time Series
+ title: Internal Helpers
+ title: API
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ms/index.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ms/index.md
new file mode 100644
index 0000000000000000000000000000000000000000..f51c43c9bd01a63f3303e4a2306449bdc31b75f9
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ms/index.md
@@ -0,0 +1,464 @@
+
+
+# 🤗 Transformers
+
+Pembelajaran Mesin terkini untuk [PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/), dan [JAX](https://jax.readthedocs.io/en/latest/).
+
+🤗 Transformers menyediakan API dan alatan untuk memuat turun dan melatih model pra-latihan terkini dengan mudah. Menggunakan model terlatih boleh mengurangkan kos pengiraan anda, jejak karbon dan menjimatkan masa serta sumber yang diperlukan untuk melatih model dari awal. Model ini menyokong tugas biasa dalam modaliti yang berbeza, seperti:
+
+📝 **Natural Language Processing**: klasifikasi teks, pengecaman entiti bernama, menjawab soalan, pemodelan bahasa, ringkasan, terjemahan, pilihan berganda dan penjanaan teks.
+
+
+## Kandungan
+
+Dokumentasi disusun kepada lima bahagian:
+
+- **MULAKAN** menyediakan lawatan pantas ke perpustakaan dan arahan pemasangan untuk bangun dan berjalan.
+- **TUTORIAL** ialah tempat yang bagus untuk bermula jika anda seorang pemula. Bahagian ini akan membantu anda memperoleh kemahiran asas yang anda perlukan untuk mula menggunakan perpustakaan.
+- **PANDUAN CARA-CARA** menunjukkan kepada anda cara untuk mencapai matlamat tertentu, seperti memperhalusi model terlatih untuk pemodelan bahasa atau cara menulis dan berkongsi model tersuai.
+- **PANDUAN KONSEP** menawarkan lebih banyak perbincangan dan penjelasan tentang konsep dan idea asas di sebalik model, tugasan dan falsafah reka bentuk 🤗 Transformers.
+- **API** menerangkan semua kelas dan fungsi:
+
+ - **KELAS UTAMA** memperincikan kelas yang paling penting seperti konfigurasi, model, tokenizer dan saluran paip.
+ - **MODEL** memperincikan kelas dan fungsi yang berkaitan dengan setiap model yang dilaksanakan dalam perpustakaan.
+ - **PEMBANTU DALAMAN** memperincikan kelas utiliti dan fungsi yang digunakan secara dalaman.
+
+### Model yang disokong
+
+
+
+1. **[ALBERT](model_doc/albert)** (from Google Research and the Toyota Technological Institute at Chicago) released with the paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://arxiv.org/abs/1909.11942), by Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
+1. **[ALIGN](model_doc/align)** (from Google Research) released with the paper [Scaling Up Visual and Vision-Language Representation Learning With Noisy Text Supervision](https://arxiv.org/abs/2102.05918) by Chao Jia, Yinfei Yang, Ye Xia, Yi-Ting Chen, Zarana Parekh, Hieu Pham, Quoc V. Le, Yunhsuan Sung, Zhen Li, Tom Duerig.
+1. **[AltCLIP](model_doc/altclip)** (from BAAI) released with the paper [AltCLIP: Altering the Language Encoder in CLIP for Extended Language Capabilities](https://arxiv.org/abs/2211.06679) by Chen, Zhongzhi and Liu, Guang and Zhang, Bo-Wen and Ye, Fulong and Yang, Qinghong and Wu, Ledell.
+1. **[Audio Spectrogram Transformer](model_doc/audio-spectrogram-transformer)** (from MIT) released with the paper [AST: Audio Spectrogram Transformer](https://arxiv.org/abs/2104.01778) by Yuan Gong, Yu-An Chung, James Glass.
+1. **[Autoformer](model_doc/autoformer)** (from Tsinghua University) released with the paper [Autoformer: Decomposition Transformers with Auto-Correlation for Long-Term Series Forecasting](https://arxiv.org/abs/2106.13008) by Haixu Wu, Jiehui Xu, Jianmin Wang, Mingsheng Long.
+1. **[BART](model_doc/bart)** (from Facebook) released with the paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://arxiv.org/abs/1910.13461) by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer.
+1. **[BARThez](model_doc/barthez)** (from École polytechnique) released with the paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321) by Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
+1. **[BARTpho](model_doc/bartpho)** (from VinAI Research) released with the paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701) by Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen.
+1. **[BEiT](model_doc/beit)** (from Microsoft) released with the paper [BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254) by Hangbo Bao, Li Dong, Furu Wei.
+1. **[BERT](model_doc/bert)** (from Google) released with the paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805) by Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova.
+1. **[BERT For Sequence Generation](model_doc/bert-generation)** (from Google) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[BERTweet](model_doc/bertweet)** (from VinAI Research) released with the paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) by Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen.
+1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BigBird-RoBERTa](model_doc/big_bird)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BioGpt](model_doc/biogpt)** (from Microsoft Research AI4Science) released with the paper [BioGPT: generative pre-trained transformer for biomedical text generation and mining](https://academic.oup.com/bib/advance-article/doi/10.1093/bib/bbac409/6713511?guestAccessKey=a66d9b5d-4f83-4017-bb52-405815c907b9) by Renqian Luo, Liai Sun, Yingce Xia, Tao Qin, Sheng Zhang, Hoifung Poon and Tie-Yan Liu.
+1. **[BiT](model_doc/bit)** (from Google AI) released with the paper [Big Transfer (BiT): General Visual Representation Learning](https://arxiv.org/abs/1912.11370) by Alexander Kolesnikov, Lucas Beyer, Xiaohua Zhai, Joan Puigcerver, Jessica Yung, Sylvain Gelly, Neil Houlsby.
+1. **[Blenderbot](model_doc/blenderbot)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BlenderbotSmall](model_doc/blenderbot-small)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BLIP](model_doc/blip)** (from Salesforce) released with the paper [BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation](https://arxiv.org/abs/2201.12086) by Junnan Li, Dongxu Li, Caiming Xiong, Steven Hoi.
+1. **[BLIP-2](model_doc/blip-2)** (from Salesforce) released with the paper [BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models](https://arxiv.org/abs/2301.12597) by Junnan Li, Dongxu Li, Silvio Savarese, Steven Hoi.
+1. **[BLOOM](model_doc/bloom)** (from BigScience workshop) released by the [BigScience Workshop](https://bigscience.huggingface.co/).
+1. **[BORT](model_doc/bort)** (from Alexa) released with the paper [Optimal Subarchitecture Extraction For BERT](https://arxiv.org/abs/2010.10499) by Adrian de Wynter and Daniel J. Perry.
+1. **[BridgeTower](model_doc/bridgetower)** (from Harbin Institute of Technology/Microsoft Research Asia/Intel Labs) released with the paper [BridgeTower: Building Bridges Between Encoders in Vision-Language Representation Learning](https://arxiv.org/abs/2206.08657) by Xiao Xu, Chenfei Wu, Shachar Rosenman, Vasudev Lal, Wanxiang Che, Nan Duan.
+1. **[Bros](model_doc/bros)** (from NAVER) released with the paper [BROS: A Pre-trained Language Model Focusing on Text and Layout for Better Key Information Extraction from Documents](https://arxiv.org/abs/2108.04539) by Teakgyu Hong, Donghyun Kim, Mingi Ji, Wonseok Hwang, Daehyun Nam, Sungrae Park.
+1. **[ByT5](model_doc/byt5)** (from Google Research) released with the paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://arxiv.org/abs/2105.13626) by Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
+1. **[CamemBERT](model_doc/camembert)** (from Inria/Facebook/Sorbonne) released with the paper [CamemBERT: a Tasty French Language Model](https://arxiv.org/abs/1911.03894) by Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot.
+1. **[CANINE](model_doc/canine)** (from Google Research) released with the paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://arxiv.org/abs/2103.06874) by Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
+1. **[Chinese-CLIP](model_doc/chinese_clip)** (from OFA-Sys) released with the paper [Chinese CLIP: Contrastive Vision-Language Pretraining in Chinese](https://arxiv.org/abs/2211.01335) by An Yang, Junshu Pan, Junyang Lin, Rui Men, Yichang Zhang, Jingren Zhou, Chang Zhou.
+1. **[CLAP](model_doc/clap)** (from LAION-AI) released with the paper [Large-scale Contrastive Language-Audio Pretraining with Feature Fusion and Keyword-to-Caption Augmentation](https://arxiv.org/abs/2211.06687) by Yusong Wu, Ke Chen, Tianyu Zhang, Yuchen Hui, Taylor Berg-Kirkpatrick, Shlomo Dubnov.
+1. **[CLIP](model_doc/clip)** (from OpenAI) released with the paper [Learning Transferable Visual Models From Natural Language Supervision](https://arxiv.org/abs/2103.00020) by Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
+1. **[CLIPSeg](model_doc/clipseg)** (from University of Göttingen) released with the paper [Image Segmentation Using Text and Image Prompts](https://arxiv.org/abs/2112.10003) by Timo Lüddecke and Alexander Ecker.
+1. **[CodeGen](model_doc/codegen)** (from Salesforce) released with the paper [A Conversational Paradigm for Program Synthesis](https://arxiv.org/abs/2203.13474) by Erik Nijkamp, Bo Pang, Hiroaki Hayashi, Lifu Tu, Huan Wang, Yingbo Zhou, Silvio Savarese, Caiming Xiong.
+1. **[Conditional DETR](model_doc/conditional_detr)** (from Microsoft Research Asia) released with the paper [Conditional DETR for Fast Training Convergence](https://arxiv.org/abs/2108.06152) by Depu Meng, Xiaokang Chen, Zejia Fan, Gang Zeng, Houqiang Li, Yuhui Yuan, Lei Sun, Jingdong Wang.
+1. **[ConvBERT](model_doc/convbert)** (from YituTech) released with the paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496) by Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
+1. **[ConvNeXT](model_doc/convnext)** (from Facebook AI) released with the paper [A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545) by Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
+1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://arxiv.org/abs/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
+1. **[CPM](model_doc/cpm)** (from Tsinghua University) released with the paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://arxiv.org/abs/2012.00413) by Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
+1. **[CPM-Ant](model_doc/cpmant)** (from OpenBMB) released by the [OpenBMB](https://www.openbmb.org/).
+1. **[CTRL](model_doc/ctrl)** (from Salesforce) released with the paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://arxiv.org/abs/1909.05858) by Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher.
+1. **[CvT](model_doc/cvt)** (from Microsoft) released with the paper [CvT: Introducing Convolutions to Vision Transformers](https://arxiv.org/abs/2103.15808) by Haiping Wu, Bin Xiao, Noel Codella, Mengchen Liu, Xiyang Dai, Lu Yuan, Lei Zhang.
+1. **[Data2Vec](model_doc/data2vec)** (from Facebook) released with the paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://arxiv.org/abs/2202.03555) by Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
+1. **[DeBERTa](model_doc/deberta)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[DeBERTa-v2](model_doc/deberta-v2)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[Decision Transformer](model_doc/decision_transformer)** (from Berkeley/Facebook/Google) released with the paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://arxiv.org/abs/2106.01345) by Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
+1. **[Deformable DETR](model_doc/deformable_detr)** (from SenseTime Research) released with the paper [Deformable DETR: Deformable Transformers for End-to-End Object Detection](https://arxiv.org/abs/2010.04159) by Xizhou Zhu, Weijie Su, Lewei Lu, Bin Li, Xiaogang Wang, Jifeng Dai.
+1. **[DeiT](model_doc/deit)** (from Facebook) released with the paper [Training data-efficient image transformers & distillation through attention](https://arxiv.org/abs/2012.12877) by Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
+1. **[DePlot](model_doc/deplot)** (from Google AI) released with the paper [DePlot: One-shot visual language reasoning by plot-to-table translation](https://arxiv.org/abs/2212.10505) by Fangyu Liu, Julian Martin Eisenschlos, Francesco Piccinno, Syrine Krichene, Chenxi Pang, Kenton Lee, Mandar Joshi, Wenhu Chen, Nigel Collier, Yasemin Altun.
+1. **[DETA](model_doc/deta)** (from The University of Texas at Austin) released with the paper [NMS Strikes Back](https://arxiv.org/abs/2212.06137) by Jeffrey Ouyang-Zhang, Jang Hyun Cho, Xingyi Zhou, Philipp Krähenbühl.
+1. **[DETR](model_doc/detr)** (from Facebook) released with the paper [End-to-End Object Detection with Transformers](https://arxiv.org/abs/2005.12872) by Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
+1. **[DialoGPT](model_doc/dialogpt)** (from Microsoft Research) released with the paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://arxiv.org/abs/1911.00536) by Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
+1. **[DiNAT](model_doc/dinat)** (from SHI Labs) released with the paper [Dilated Neighborhood Attention Transformer](https://arxiv.org/abs/2209.15001) by Ali Hassani and Humphrey Shi.
+1. **[DistilBERT](model_doc/distilbert)** (from HuggingFace), released together with the paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://arxiv.org/abs/1910.01108) by Victor Sanh, Lysandre Debut and Thomas Wolf. The same method has been applied to compress GPT2 into [DistilGPT2](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), RoBERTa into [DistilRoBERTa](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), Multilingual BERT into [DistilmBERT](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation) and a German version of DistilBERT.
+1. **[DiT](model_doc/dit)** (from Microsoft Research) released with the paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://arxiv.org/abs/2203.02378) by Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
+1. **[Donut](model_doc/donut)** (from NAVER), released together with the paper [OCR-free Document Understanding Transformer](https://arxiv.org/abs/2111.15664) by Geewook Kim, Teakgyu Hong, Moonbin Yim, Jeongyeon Nam, Jinyoung Park, Jinyeong Yim, Wonseok Hwang, Sangdoo Yun, Dongyoon Han, Seunghyun Park.
+1. **[DPR](model_doc/dpr)** (from Facebook) released with the paper [Dense Passage Retrieval for Open-Domain Question Answering](https://arxiv.org/abs/2004.04906) by Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih.
+1. **[DPT](master/model_doc/dpt)** (from Intel Labs) released with the paper [Vision Transformers for Dense Prediction](https://arxiv.org/abs/2103.13413) by René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
+1. **[EfficientFormer](model_doc/efficientformer)** (from Snap Research) released with the paper [EfficientFormer: Vision Transformers at MobileNetSpeed](https://arxiv.org/abs/2206.01191) by Yanyu Li, Geng Yuan, Yang Wen, Ju Hu, Georgios Evangelidis, Sergey Tulyakov, Yanzhi Wang, Jian Ren.
+1. **[EfficientNet](model_doc/efficientnet)** (from Google Brain) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://arxiv.org/abs/1905.11946) by Mingxing Tan, Quoc V. Le.
+1. **[ELECTRA](model_doc/electra)** (from Google Research/Stanford University) released with the paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://arxiv.org/abs/2003.10555) by Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
+1. **[EncoderDecoder](model_doc/encoder-decoder)** (from Google Research) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[ERNIE](model_doc/ernie)** (from Baidu) released with the paper [ERNIE: Enhanced Representation through Knowledge Integration](https://arxiv.org/abs/1904.09223) by Yu Sun, Shuohuan Wang, Yukun Li, Shikun Feng, Xuyi Chen, Han Zhang, Xin Tian, Danxiang Zhu, Hao Tian, Hua Wu.
+1. **[ErnieM](model_doc/ernie_m)** (from Baidu) released with the paper [ERNIE-M: Enhanced Multilingual Representation by Aligning Cross-lingual Semantics with Monolingual Corpora](https://arxiv.org/abs/2012.15674) by Xuan Ouyang, Shuohuan Wang, Chao Pang, Yu Sun, Hao Tian, Hua Wu, Haifeng Wang.
+1. **[ESM](model_doc/esm)** (from Meta AI) are transformer protein language models. **ESM-1b** was released with the paper [Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences](https://www.pnas.org/content/118/15/e2016239118) by Alexander Rives, Joshua Meier, Tom Sercu, Siddharth Goyal, Zeming Lin, Jason Liu, Demi Guo, Myle Ott, C. Lawrence Zitnick, Jerry Ma, and Rob Fergus. **ESM-1v** was released with the paper [Language models enable zero-shot prediction of the effects of mutations on protein function](https://doi.org/10.1101/2021.07.09.450648) by Joshua Meier, Roshan Rao, Robert Verkuil, Jason Liu, Tom Sercu and Alexander Rives. **ESM-2 and ESMFold** were released with the paper [Language models of protein sequences at the scale of evolution enable accurate structure prediction](https://doi.org/10.1101/2022.07.20.500902) by Zeming Lin, Halil Akin, Roshan Rao, Brian Hie, Zhongkai Zhu, Wenting Lu, Allan dos Santos Costa, Maryam Fazel-Zarandi, Tom Sercu, Sal Candido, Alexander Rives.
+1. **[FLAN-T5](model_doc/flan-t5)** (from Google AI) released in the repository [google-research/t5x](https://github.com/google-research/t5x/blob/main/docs/models.md#flan-t5-checkpoints) by Hyung Won Chung, Le Hou, Shayne Longpre, Barret Zoph, Yi Tay, William Fedus, Eric Li, Xuezhi Wang, Mostafa Dehghani, Siddhartha Brahma, Albert Webson, Shixiang Shane Gu, Zhuyun Dai, Mirac Suzgun, Xinyun Chen, Aakanksha Chowdhery, Sharan Narang, Gaurav Mishra, Adams Yu, Vincent Zhao, Yanping Huang, Andrew Dai, Hongkun Yu, Slav Petrov, Ed H. Chi, Jeff Dean, Jacob Devlin, Adam Roberts, Denny Zhou, Quoc V. Le, and Jason Wei
+1. **[FLAN-UL2](model_doc/flan-ul2)** (from Google AI) released in the repository [google-research/t5x](https://github.com/google-research/t5x/blob/main/docs/models.md#flan-ul2-checkpoints) by Hyung Won Chung, Le Hou, Shayne Longpre, Barret Zoph, Yi Tay, William Fedus, Eric Li, Xuezhi Wang, Mostafa Dehghani, Siddhartha Brahma, Albert Webson, Shixiang Shane Gu, Zhuyun Dai, Mirac Suzgun, Xinyun Chen, Aakanksha Chowdhery, Sharan Narang, Gaurav Mishra, Adams Yu, Vincent Zhao, Yanping Huang, Andrew Dai, Hongkun Yu, Slav Petrov, Ed H. Chi, Jeff Dean, Jacob Devlin, Adam Roberts, Denny Zhou, Quoc V. Le, and Jason Wei
+1. **[FlauBERT](model_doc/flaubert)** (from CNRS) released with the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://arxiv.org/abs/1912.05372) by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
+1. **[FLAVA](model_doc/flava)** (from Facebook AI) released with the paper [FLAVA: A Foundational Language And Vision Alignment Model](https://arxiv.org/abs/2112.04482) by Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, and Douwe Kiela.
+1. **[FNet](model_doc/fnet)** (from Google Research) released with the paper [FNet: Mixing Tokens with Fourier Transforms](https://arxiv.org/abs/2105.03824) by James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
+1. **[FocalNet](model_doc/focalnet)** (from Microsoft Research) released with the paper [Focal Modulation Networks](https://arxiv.org/abs/2203.11926) by Jianwei Yang, Chunyuan Li, Xiyang Dai, Lu Yuan, Jianfeng Gao.
+1. **[Funnel Transformer](model_doc/funnel)** (from CMU/Google Brain) released with the paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://arxiv.org/abs/2006.03236) by Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
+1. **[GIT](model_doc/git)** (from Microsoft Research) released with the paper [GIT: A Generative Image-to-text Transformer for Vision and Language](https://arxiv.org/abs/2205.14100) by Jianfeng Wang, Zhengyuan Yang, Xiaowei Hu, Linjie Li, Kevin Lin, Zhe Gan, Zicheng Liu, Ce Liu, Lijuan Wang.
+1. **[GLPN](model_doc/glpn)** (from KAIST) released with the paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://arxiv.org/abs/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
+1. **[GPT](model_doc/openai-gpt)** (from OpenAI) released with the paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) by Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever.
+1. **[GPT Neo](model_doc/gpt_neo)** (from EleutherAI) released in the repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) by Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy.
+1. **[GPT NeoX](model_doc/gpt_neox)** (from EleutherAI) released with the paper [GPT-NeoX-20B: An Open-Source Autoregressive Language Model](https://arxiv.org/abs/2204.06745) by Sid Black, Stella Biderman, Eric Hallahan, Quentin Anthony, Leo Gao, Laurence Golding, Horace He, Connor Leahy, Kyle McDonell, Jason Phang, Michael Pieler, USVSN Sai Prashanth, Shivanshu Purohit, Laria Reynolds, Jonathan Tow, Ben Wang, Samuel Weinbach
+1. **[GPT NeoX Japanese](model_doc/gpt_neox_japanese)** (from ABEJA) released by Shinya Otani, Takayoshi Makabe, Anuj Arora, and Kyo Hattori.
+1. **[GPT-2](model_doc/gpt2)** (from OpenAI) released with the paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) by Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever.
+1. **[GPT-J](model_doc/gptj)** (from EleutherAI) released in the repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) by Ben Wang and Aran Komatsuzaki.
+1. **[GPT-Sw3](model_doc/gpt-sw3)** (from AI-Sweden) released with the paper [Lessons Learned from GPT-SW3: Building the First Large-Scale Generative Language Model for Swedish](http://www.lrec-conf.org/proceedings/lrec2022/pdf/2022.lrec-1.376.pdf) by Ariel Ekgren, Amaru Cuba Gyllensten, Evangelia Gogoulou, Alice Heiman, Severine Verlinden, Joey Öhman, Fredrik Carlsson, Magnus Sahlgren.
+1. **[GPTBigCode](model_doc/gpt_bigcode)** (from BigCode) released with the paper [SantaCoder: don't reach for the stars!](https://arxiv.org/abs/2301.03988) by Loubna Ben Allal, Raymond Li, Denis Kocetkov, Chenghao Mou, Christopher Akiki, Carlos Munoz Ferrandis, Niklas Muennighoff, Mayank Mishra, Alex Gu, Manan Dey, Logesh Kumar Umapathi, Carolyn Jane Anderson, Yangtian Zi, Joel Lamy Poirier, Hailey Schoelkopf, Sergey Troshin, Dmitry Abulkhanov, Manuel Romero, Michael Lappert, Francesco De Toni, Bernardo García del Río, Qian Liu, Shamik Bose, Urvashi Bhattacharyya, Terry Yue Zhuo, Ian Yu, Paulo Villegas, Marco Zocca, Sourab Mangrulkar, David Lansky, Huu Nguyen, Danish Contractor, Luis Villa, Jia Li, Dzmitry Bahdanau, Yacine Jernite, Sean Hughes, Daniel Fried, Arjun Guha, Harm de Vries, Leandro von Werra.
+1. **[GPTSAN-japanese](model_doc/gptsan-japanese)** released in the repository [tanreinama/GPTSAN](https://github.com/tanreinama/GPTSAN/blob/main/report/model.md) by Toshiyuki Sakamoto(tanreinama).
+1. **[Graphormer](model_doc/graphormer)** (from Microsoft) released with the paper [Do Transformers Really Perform Bad for Graph Representation?](https://arxiv.org/abs/2106.05234) by Chengxuan Ying, Tianle Cai, Shengjie Luo, Shuxin Zheng, Guolin Ke, Di He, Yanming Shen, Tie-Yan Liu.
+1. **[GroupViT](model_doc/groupvit)** (from UCSD, NVIDIA) released with the paper [GroupViT: Semantic Segmentation Emerges from Text Supervision](https://arxiv.org/abs/2202.11094) by Jiarui Xu, Shalini De Mello, Sifei Liu, Wonmin Byeon, Thomas Breuel, Jan Kautz, Xiaolong Wang.
+1. **[Hubert](model_doc/hubert)** (from Facebook) released with the paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://arxiv.org/abs/2106.07447) by Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
+1. **[I-BERT](model_doc/ibert)** (from Berkeley) released with the paper [I-BERT: Integer-only BERT Quantization](https://arxiv.org/abs/2101.01321) by Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
+1. **[ImageGPT](model_doc/imagegpt)** (from OpenAI) released with the paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) by Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
+1. **[Informer](model_doc/informer)** (from Beihang University, UC Berkeley, Rutgers University, SEDD Company) released with the paper [Informer: Beyond Efficient Transformer for Long Sequence Time-Series Forecasting](https://arxiv.org/abs/2012.07436) by Haoyi Zhou, Shanghang Zhang, Jieqi Peng, Shuai Zhang, Jianxin Li, Hui Xiong, and Wancai Zhang.
+1. **[Jukebox](model_doc/jukebox)** (from OpenAI) released with the paper [Jukebox: A Generative Model for Music](https://arxiv.org/pdf/2005.00341.pdf) by Prafulla Dhariwal, Heewoo Jun, Christine Payne, Jong Wook Kim, Alec Radford, Ilya Sutskever.
+1. **[LayoutLM](model_doc/layoutlm)** (from Microsoft Research Asia) released with the paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://arxiv.org/abs/1912.13318) by Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
+1. **[LayoutLMv2](model_doc/layoutlmv2)** (from Microsoft Research Asia) released with the paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://arxiv.org/abs/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
+1. **[LayoutLMv3](model_doc/layoutlmv3)** (from Microsoft Research Asia) released with the paper [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://arxiv.org/abs/2204.08387) by Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei.
+1. **[LayoutXLM](model_doc/layoutxlm)** (from Microsoft Research Asia) released with the paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://arxiv.org/abs/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
+1. **[LED](model_doc/led)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LeViT](model_doc/levit)** (from Meta AI) released with the paper [LeViT: A Vision Transformer in ConvNet's Clothing for Faster Inference](https://arxiv.org/abs/2104.01136) by Ben Graham, Alaaeldin El-Nouby, Hugo Touvron, Pierre Stock, Armand Joulin, Hervé Jégou, Matthijs Douze.
+1. **[LiLT](model_doc/lilt)** (from South China University of Technology) released with the paper [LiLT: A Simple yet Effective Language-Independent Layout Transformer for Structured Document Understanding](https://arxiv.org/abs/2202.13669) by Jiapeng Wang, Lianwen Jin, Kai Ding.
+1. **[LLaMA](model_doc/llama)** (from The FAIR team of Meta AI) released with the paper [LLaMA: Open and Efficient Foundation Language Models](https://arxiv.org/abs/2302.13971) by Hugo Touvron, Thibaut Lavril, Gautier Izacard, Xavier Martinet, Marie-Anne Lachaux, Timothée Lacroix, Baptiste Rozière, Naman Goyal, Eric Hambro, Faisal Azhar, Aurelien Rodriguez, Armand Joulin, Edouard Grave, Guillaume Lample.
+1. **[Longformer](model_doc/longformer)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LongT5](model_doc/longt5)** (from Google AI) released with the paper [LongT5: Efficient Text-To-Text Transformer for Long Sequences](https://arxiv.org/abs/2112.07916) by Mandy Guo, Joshua Ainslie, David Uthus, Santiago Ontanon, Jianmo Ni, Yun-Hsuan Sung, Yinfei Yang.
+1. **[LUKE](model_doc/luke)** (from Studio Ousia) released with the paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://arxiv.org/abs/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
+1. **[LXMERT](model_doc/lxmert)** (from UNC Chapel Hill) released with the paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://arxiv.org/abs/1908.07490) by Hao Tan and Mohit Bansal.
+1. **[M-CTC-T](model_doc/mctct)** (from Facebook) released with the paper [Pseudo-Labeling For Massively Multilingual Speech Recognition](https://arxiv.org/abs/2111.00161) by Loren Lugosch, Tatiana Likhomanenko, Gabriel Synnaeve, and Ronan Collobert.
+1. **[M2M100](model_doc/m2m_100)** (from Facebook) released with the paper [Beyond English-Centric Multilingual Machine Translation](https://arxiv.org/abs/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
+1. **[MarianMT](model_doc/marian)** Machine translation models trained using [OPUS](http://opus.nlpl.eu/) data by Jörg Tiedemann. The [Marian Framework](https://marian-nmt.github.io/) is being developed by the Microsoft Translator Team.
+1. **[MarkupLM](model_doc/markuplm)** (from Microsoft Research Asia) released with the paper [MarkupLM: Pre-training of Text and Markup Language for Visually-rich Document Understanding](https://arxiv.org/abs/2110.08518) by Junlong Li, Yiheng Xu, Lei Cui, Furu Wei.
+1. **[Mask2Former](model_doc/mask2former)** (from FAIR and UIUC) released with the paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://arxiv.org/abs/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
+1. **[MaskFormer](model_doc/maskformer)** (from Meta and UIUC) released with the paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://arxiv.org/abs/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
+1. **[MatCha](model_doc/matcha)** (from Google AI) released with the paper [MatCha: Enhancing Visual Language Pretraining with Math Reasoning and Chart Derendering](https://arxiv.org/abs/2212.09662) by Fangyu Liu, Francesco Piccinno, Syrine Krichene, Chenxi Pang, Kenton Lee, Mandar Joshi, Yasemin Altun, Nigel Collier, Julian Martin Eisenschlos.
+1. **[mBART](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://arxiv.org/abs/2001.08210) by Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
+1. **[mBART-50](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://arxiv.org/abs/2008.00401) by Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
+1. **[MEGA](model_doc/mega)** (from Meta/USC/CMU/SJTU) released with the paper [Mega: Moving Average Equipped Gated Attention](https://arxiv.org/abs/2209.10655) by Xuezhe Ma, Chunting Zhou, Xiang Kong, Junxian He, Liangke Gui, Graham Neubig, Jonathan May, and Luke Zettlemoyer.
+1. **[Megatron-BERT](model_doc/megatron-bert)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[MGP-STR](model_doc/mgp-str)** (from Alibaba Research) released with the paper [Multi-Granularity Prediction for Scene Text Recognition](https://arxiv.org/abs/2209.03592) by Peng Wang, Cheng Da, and Cong Yao.
+1. **[mLUKE](model_doc/mluke)** (from Studio Ousia) released with the paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://arxiv.org/abs/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka.
+1. **[MobileBERT](model_doc/mobilebert)** (from CMU/Google Brain) released with the paper [MobileBERT: a Compact Task-Agnostic BERT for Resource-Limited Devices](https://arxiv.org/abs/2004.02984) by Zhiqing Sun, Hongkun Yu, Xiaodan Song, Renjie Liu, Yiming Yang, and Denny Zhou.
+1. **[MobileNetV1](model_doc/mobilenet_v1)** (from Google Inc.) released with the paper [MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications](https://arxiv.org/abs/1704.04861) by Andrew G. Howard, Menglong Zhu, Bo Chen, Dmitry Kalenichenko, Weijun Wang, Tobias Weyand, Marco Andreetto, Hartwig Adam.
+1. **[MobileNetV2](model_doc/mobilenet_v2)** (from Google Inc.) released with the paper [MobileNetV2: Inverted Residuals and Linear Bottlenecks](https://arxiv.org/abs/1801.04381) by Mark Sandler, Andrew Howard, Menglong Zhu, Andrey Zhmoginov, Liang-Chieh Chen.
+1. **[MobileViT](model_doc/mobilevit)** (from Apple) released with the paper [MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer](https://arxiv.org/abs/2110.02178) by Sachin Mehta and Mohammad Rastegari.
+1. **[MPNet](model_doc/mpnet)** (from Microsoft Research) released with the paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://arxiv.org/abs/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
+1. **[MT5](model_doc/mt5)** (from Google AI) released with the paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://arxiv.org/abs/2010.11934) by Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
+1. **[MVP](model_doc/mvp)** (from RUC AI Box) released with the paper [MVP: Multi-task Supervised Pre-training for Natural Language Generation](https://arxiv.org/abs/2206.12131) by Tianyi Tang, Junyi Li, Wayne Xin Zhao and Ji-Rong Wen.
+1. **[NAT](model_doc/nat)** (from SHI Labs) released with the paper [Neighborhood Attention Transformer](https://arxiv.org/abs/2204.07143) by Ali Hassani, Steven Walton, Jiachen Li, Shen Li, and Humphrey Shi.
+1. **[Nezha](model_doc/nezha)** (from Huawei Noah’s Ark Lab) released with the paper [NEZHA: Neural Contextualized Representation for Chinese Language Understanding](https://arxiv.org/abs/1909.00204) by Junqiu Wei, Xiaozhe Ren, Xiaoguang Li, Wenyong Huang, Yi Liao, Yasheng Wang, Jiashu Lin, Xin Jiang, Xiao Chen and Qun Liu.
+1. **[NLLB](model_doc/nllb)** (from Meta) released with the paper [No Language Left Behind: Scaling Human-Centered Machine Translation](https://arxiv.org/abs/2207.04672) by the NLLB team.
+1. **[NLLB-MOE](model_doc/nllb-moe)** (from Meta) released with the paper [No Language Left Behind: Scaling Human-Centered Machine Translation](https://arxiv.org/abs/2207.04672) by the NLLB team.
+1. **[Nyströmformer](model_doc/nystromformer)** (from the University of Wisconsin - Madison) released with the paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://arxiv.org/abs/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
+1. **[OneFormer](model_doc/oneformer)** (from SHI Labs) released with the paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
+1. **[OpenLlama](model_doc/open-llama)** (from [s-JoL](https://huggingface.co/s-JoL)) released on GitHub (now removed).
+1. **[OPT](master/model_doc/opt)** (from Meta AI) released with the paper [OPT: Open Pre-trained Transformer Language Models](https://arxiv.org/abs/2205.01068) by Susan Zhang, Stephen Roller, Naman Goyal, Mikel Artetxe, Moya Chen, Shuohui Chen et al.
+1. **[OWL-ViT](model_doc/owlvit)** (from Google AI) released with the paper [Simple Open-Vocabulary Object Detection with Vision Transformers](https://arxiv.org/abs/2205.06230) by Matthias Minderer, Alexey Gritsenko, Austin Stone, Maxim Neumann, Dirk Weissenborn, Alexey Dosovitskiy, Aravindh Mahendran, Anurag Arnab, Mostafa Dehghani, Zhuoran Shen, Xiao Wang, Xiaohua Zhai, Thomas Kipf, and Neil Houlsby.
+1. **[Pegasus](model_doc/pegasus)** (from Google) released with the paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/abs/1912.08777) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu.
+1. **[PEGASUS-X](model_doc/pegasus_x)** (from Google) released with the paper [Investigating Efficiently Extending Transformers for Long Input Summarization](https://arxiv.org/abs/2208.04347) by Jason Phang, Yao Zhao, and Peter J. Liu.
+1. **[Perceiver IO](model_doc/perceiver)** (from Deepmind) released with the paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://arxiv.org/abs/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
+1. **[PhoBERT](model_doc/phobert)** (from VinAI Research) released with the paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) by Dat Quoc Nguyen and Anh Tuan Nguyen.
+1. **[Pix2Struct](model_doc/pix2struct)** (from Google) released with the paper [Pix2Struct: Screenshot Parsing as Pretraining for Visual Language Understanding](https://arxiv.org/abs/2210.03347) by Kenton Lee, Mandar Joshi, Iulia Turc, Hexiang Hu, Fangyu Liu, Julian Eisenschlos, Urvashi Khandelwal, Peter Shaw, Ming-Wei Chang, Kristina Toutanova.
+1. **[PLBart](model_doc/plbart)** (from UCLA NLP) released with the paper [Unified Pre-training for Program Understanding and Generation](https://arxiv.org/abs/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
+1. **[PoolFormer](model_doc/poolformer)** (from Sea AI Labs) released with the paper [MetaFormer is Actually What You Need for Vision](https://arxiv.org/abs/2111.11418) by Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng.
+1. **[ProphetNet](model_doc/prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[QDQBert](model_doc/qdqbert)** (from NVIDIA) released with the paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://arxiv.org/abs/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius.
+1. **[RAG](model_doc/rag)** (from Facebook) released with the paper [Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks](https://arxiv.org/abs/2005.11401) by Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, Douwe Kiela.
+1. **[REALM](model_doc/realm.html)** (from Google Research) released with the paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://arxiv.org/abs/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang.
+1. **[Reformer](model_doc/reformer)** (from Google Research) released with the paper [Reformer: The Efficient Transformer](https://arxiv.org/abs/2001.04451) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
+1. **[RegNet](model_doc/regnet)** (from META Platforms) released with the paper [Designing Network Design Space](https://arxiv.org/abs/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
+1. **[RemBERT](model_doc/rembert)** (from Google Research) released with the paper [Rethinking embedding coupling in pre-trained language models](https://arxiv.org/abs/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
+1. **[ResNet](model_doc/resnet)** (from Microsoft Research) released with the paper [Deep Residual Learning for Image Recognition](https://arxiv.org/abs/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
+1. **[RoBERTa](model_doc/roberta)** (from Facebook), released together with the paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://arxiv.org/abs/1907.11692) by Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
+1. **[RoBERTa-PreLayerNorm](model_doc/roberta-prelayernorm)** (from Facebook) released with the paper [fairseq: A Fast, Extensible Toolkit for Sequence Modeling](https://arxiv.org/abs/1904.01038) by Myle Ott, Sergey Edunov, Alexei Baevski, Angela Fan, Sam Gross, Nathan Ng, David Grangier, Michael Auli.
+1. **[RoCBert](model_doc/roc_bert)** (from WeChatAI) released with the paper [RoCBert: Robust Chinese Bert with Multimodal Contrastive Pretraining](https://aclanthology.org/2022.acl-long.65.pdf) by HuiSu, WeiweiShi, XiaoyuShen, XiaoZhou, TuoJi, JiaruiFang, JieZhou.
+1. **[RoFormer](model_doc/roformer)** (from ZhuiyiTechnology), released together with the paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/abs/2104.09864) by Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu.
+1. **[RWKV](model_doc/rwkv)** (from Bo Peng), released on [this repo](https://github.com/BlinkDL/RWKV-LM) by Bo Peng.
+1. **[SegFormer](model_doc/segformer)** (from NVIDIA) released with the paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://arxiv.org/abs/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
+1. **[Segment Anything](model_doc/sam)** (from Meta AI) released with the paper [Segment Anything](https://arxiv.org/pdf/2304.02643v1.pdf) by Alexander Kirillov, Eric Mintun, Nikhila Ravi, Hanzi Mao, Chloe Rolland, Laura Gustafson, Tete Xiao, Spencer Whitehead, Alex Berg, Wan-Yen Lo, Piotr Dollar, Ross Girshick.
+1. **[SEW](model_doc/sew)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SEW-D](model_doc/sew_d)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SpeechT5](model_doc/speecht5)** (from Microsoft Research) released with the paper [SpeechT5: Unified-Modal Encoder-Decoder Pre-Training for Spoken Language Processing](https://arxiv.org/abs/2110.07205) by Junyi Ao, Rui Wang, Long Zhou, Chengyi Wang, Shuo Ren, Yu Wu, Shujie Liu, Tom Ko, Qing Li, Yu Zhang, Zhihua Wei, Yao Qian, Jinyu Li, Furu Wei.
+1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (from Facebook), released together with the paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
+1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (from Facebook), released together with the paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://arxiv.org/abs/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
+1. **[Splinter](model_doc/splinter)** (from Tel Aviv University), released together with the paper [Few-Shot Question Answering by Pretraining Span Selection](https://arxiv.org/abs/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
+1. **[SqueezeBERT](model_doc/squeezebert)** (from Berkeley) released with the paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://arxiv.org/abs/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer.
+1. **[SwiftFormer](model_doc/swiftformer)** (from MBZUAI) released with the paper [SwiftFormer: Efficient Additive Attention for Transformer-based Real-time Mobile Vision Applications](https://arxiv.org/abs/2303.15446) by Abdelrahman Shaker, Muhammad Maaz, Hanoona Rasheed, Salman Khan, Ming-Hsuan Yang, Fahad Shahbaz Khan.
+1. **[Swin Transformer](model_doc/swin)** (from Microsoft) released with the paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030) by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
+1. **[Swin Transformer V2](model_doc/swinv2)** (from Microsoft) released with the paper [Swin Transformer V2: Scaling Up Capacity and Resolution](https://arxiv.org/abs/2111.09883) by Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo.
+1. **[Swin2SR](model_doc/swin2sr)** (from University of Würzburg) released with the paper [Swin2SR: SwinV2 Transformer for Compressed Image Super-Resolution and Restoration](https://arxiv.org/abs/2209.11345) by Marcos V. Conde, Ui-Jin Choi, Maxime Burchi, Radu Timofte.
+1. **[SwitchTransformers](model_doc/switch_transformers)** (from Google) released with the paper [Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity](https://arxiv.org/abs/2101.03961) by William Fedus, Barret Zoph, Noam Shazeer.
+1. **[T5](model_doc/t5)** (from Google AI) released with the paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[T5v1.1](model_doc/t5v1.1)** (from Google AI) released in the repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[Table Transformer](model_doc/table-transformer)** (from Microsoft Research) released with the paper [PubTables-1M: Towards Comprehensive Table Extraction From Unstructured Documents](https://arxiv.org/abs/2110.00061) by Brandon Smock, Rohith Pesala, Robin Abraham.
+1. **[TAPAS](model_doc/tapas)** (from Google AI) released with the paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://arxiv.org/abs/2004.02349) by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos.
+1. **[TAPEX](model_doc/tapex)** (from Microsoft Research) released with the paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://arxiv.org/abs/2107.07653) by Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
+1. **[Time Series Transformer](model_doc/time_series_transformer)** (from HuggingFace).
+1. **[TimeSformer](model_doc/timesformer)** (from Facebook) released with the paper [Is Space-Time Attention All You Need for Video Understanding?](https://arxiv.org/abs/2102.05095) by Gedas Bertasius, Heng Wang, Lorenzo Torresani.
+1. **[Trajectory Transformer](model_doc/trajectory_transformers)** (from the University of California at Berkeley) released with the paper [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://arxiv.org/abs/2106.02039) by Michael Janner, Qiyang Li, Sergey Levine
+1. **[Transformer-XL](model_doc/transfo-xl)** (from Google/CMU) released with the paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://arxiv.org/abs/1901.02860) by Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
+1. **[TrOCR](model_doc/trocr)** (from Microsoft), released together with the paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://arxiv.org/abs/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
+1. **[TVLT](model_doc/tvlt)** (from UNC Chapel Hill) released with the paper [TVLT: Textless Vision-Language Transformer](https://arxiv.org/abs/2209.14156) by Zineng Tang, Jaemin Cho, Yixin Nie, Mohit Bansal.
+1. **[TVP](model_doc/tvp)** (from Intel) released with the paper [Text-Visual Prompting for Efficient 2D Temporal Video Grounding](https://arxiv.org/abs/2303.04995) by Yimeng Zhang, Xin Chen, Jinghan Jia, Sijia Liu, Ke Ding.
+1. **[UL2](model_doc/ul2)** (from Google Research) released with the paper [Unifying Language Learning Paradigms](https://arxiv.org/abs/2205.05131v1) by Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler
+1. **[UniSpeech](model_doc/unispeech)** (from Microsoft Research) released with the paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://arxiv.org/abs/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
+1. **[UniSpeechSat](model_doc/unispeech-sat)** (from Microsoft Research) released with the paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://arxiv.org/abs/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
+1. **[UPerNet](model_doc/upernet)** (from Peking University) released with the paper [Unified Perceptual Parsing for Scene Understanding](https://arxiv.org/abs/1807.10221) by Tete Xiao, Yingcheng Liu, Bolei Zhou, Yuning Jiang, Jian Sun.
+1. **[VAN](model_doc/van)** (from Tsinghua University and Nankai University) released with the paper [Visual Attention Network](https://arxiv.org/abs/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
+1. **[VideoMAE](model_doc/videomae)** (from Multimedia Computing Group, Nanjing University) released with the paper [VideoMAE: Masked Autoencoders are Data-Efficient Learners for Self-Supervised Video Pre-Training](https://arxiv.org/abs/2203.12602) by Zhan Tong, Yibing Song, Jue Wang, Limin Wang.
+1. **[ViLT](model_doc/vilt)** (from NAVER AI Lab/Kakao Enterprise/Kakao Brain) released with the paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://arxiv.org/abs/2102.03334) by Wonjae Kim, Bokyung Son, Ildoo Kim.
+1. **[Vision Transformer (ViT)](model_doc/vit)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[VisualBERT](model_doc/visual_bert)** (from UCLA NLP) released with the paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://arxiv.org/pdf/1908.03557) by Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
+1. **[ViT Hybrid](model_doc/vit_hybrid)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[ViTMAE](model_doc/vit_mae)** (from Meta AI) released with the paper [Masked Autoencoders Are Scalable Vision Learners](https://arxiv.org/abs/2111.06377) by Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
+1. **[ViTMSN](model_doc/vit_msn)** (from Meta AI) released with the paper [Masked Siamese Networks for Label-Efficient Learning](https://arxiv.org/abs/2204.07141) by Mahmoud Assran, Mathilde Caron, Ishan Misra, Piotr Bojanowski, Florian Bordes, Pascal Vincent, Armand Joulin, Michael Rabbat, Nicolas Ballas.
+1. **[Wav2Vec2](model_doc/wav2vec2)** (from Facebook AI) released with the paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://arxiv.org/abs/2006.11477) by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
+1. **[Wav2Vec2-Conformer](model_doc/wav2vec2-conformer)** (from Facebook AI) released with the paper [FAIRSEQ S2T: Fast Speech-to-Text Modeling with FAIRSEQ](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Sravya Popuri, Dmytro Okhonko, Juan Pino.
+1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (from Facebook AI) released with the paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://arxiv.org/abs/2109.11680) by Qiantong Xu, Alexei Baevski, Michael Auli.
+1. **[WavLM](model_doc/wavlm)** (from Microsoft Research) released with the paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://arxiv.org/abs/2110.13900) by Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
+1. **[Whisper](model_doc/whisper)** (from OpenAI) released with the paper [Robust Speech Recognition via Large-Scale Weak Supervision](https://cdn.openai.com/papers/whisper.pdf) by Alec Radford, Jong Wook Kim, Tao Xu, Greg Brockman, Christine McLeavey, Ilya Sutskever.
+1. **[X-CLIP](model_doc/xclip)** (from Microsoft Research) released with the paper [Expanding Language-Image Pretrained Models for General Video Recognition](https://arxiv.org/abs/2208.02816) by Bolin Ni, Houwen Peng, Minghao Chen, Songyang Zhang, Gaofeng Meng, Jianlong Fu, Shiming Xiang, Haibin Ling.
+1. **[X-MOD](model_doc/xmod)** (from Meta AI) released with the paper [Lifting the Curse of Multilinguality by Pre-training Modular Transformers](http://dx.doi.org/10.18653/v1/2022.naacl-main.255) by Jonas Pfeiffer, Naman Goyal, Xi Lin, Xian Li, James Cross, Sebastian Riedel, Mikel Artetxe.
+1. **[XGLM](model_doc/xglm)** (From Facebook AI) released with the paper [Few-shot Learning with Multilingual Language Models](https://arxiv.org/abs/2112.10668) by Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
+1. **[XLM](model_doc/xlm)** (from Facebook) released together with the paper [Cross-lingual Language Model Pretraining](https://arxiv.org/abs/1901.07291) by Guillaume Lample and Alexis Conneau.
+1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (from Facebook AI), released together with the paper [Unsupervised Cross-lingual Representation Learning at Scale](https://arxiv.org/abs/1911.02116) by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
+1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (from Facebook AI), released together with the paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://arxiv.org/abs/2105.00572) by Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
+1. **[XLM-V](model_doc/xlm-v)** (from Meta AI) released with the paper [XLM-V: Overcoming the Vocabulary Bottleneck in Multilingual Masked Language Models](https://arxiv.org/abs/2301.10472) by Davis Liang, Hila Gonen, Yuning Mao, Rui Hou, Naman Goyal, Marjan Ghazvininejad, Luke Zettlemoyer, Madian Khabsa.
+1. **[XLNet](model_doc/xlnet)** (from Google/CMU) released with the paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://arxiv.org/abs/1906.08237) by Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
+1. **[XLS-R](model_doc/xls_r)** (from Facebook AI) released with the paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://arxiv.org/abs/2111.09296) by Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
+1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (from Facebook AI) released with the paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://arxiv.org/abs/2006.13979) by Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
+1. **[YOLOS](model_doc/yolos)** (from Huazhong University of Science & Technology) released with the paper [You Only Look at One Sequence: Rethinking Transformer in Vision through Object Detection](https://arxiv.org/abs/2106.00666) by Yuxin Fang, Bencheng Liao, Xinggang Wang, Jiemin Fang, Jiyang Qi, Rui Wu, Jianwei Niu, Wenyu Liu.
+1. **[YOSO](model_doc/yoso)** (from the University of Wisconsin - Madison) released with the paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://arxiv.org/abs/2111.09714) by Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
+
+
+### Rangka kerja yang disokong
+
+Jadual di bawah mewakili sokongan semasa dalam perpustakaan untuk setiap model tersebut, sama ada model tersebut mempunyai Python
+tokenizer (dipanggil ""lambat""). Tokenizer ""pantas"" yang disokong oleh perpustakaan Tokenizers 🤗, sama ada mereka mempunyai sokongan dalam Jax (melalui
+Flax), PyTorch, dan/atau TensorFlow.
+
+
+
+| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
+|:-----------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
+| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| ALIGN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| AltCLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Audio Spectrogram Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Autoformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
+| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
+| BigBird-Pegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
+| BioGpt | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BiT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BLIP | ❌ | ❌ | ✅ | ✅ | ❌ |
+| BLIP-2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| BLOOM | ❌ | ✅ | ✅ | ❌ | ❌ |
+| BridgeTower | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Bros | ✅ | ✅ | ✅ | ❌ | ❌ |
+| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| CANINE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Chinese-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CLAP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
+| CLIPSeg | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CodeGen | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Conditional DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ConvNeXT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| ConvNeXTV2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CPM-Ant | ✅ | ❌ | ✅ | ❌ | ❌ |
+| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| CvT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecVision | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Deformable DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeiT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DETA | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DiNAT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| DonutSwin | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| EfficientFormer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| EfficientNet | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ERNIE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ErnieM | ✅ | ❌ | ✅ | ❌ | ❌ |
+| ESM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FLAVA | ❌ | ❌ | ✅ | ❌ | ❌ |
+| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
+| FocalNet | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| GIT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
+| GPT NeoX | ❌ | ✅ | ✅ | ❌ | ❌ |
+| GPT NeoX Japanese | ✅ | ❌ | ✅ | ❌ | ❌ |
+| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
+| GPT-Sw3 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| GPTBigCode | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPTSAN-japanese | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Graphormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GroupViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
+| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Informer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Jukebox | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
+| LayoutLMv3 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LeViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LiLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LLaMA | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LongT5 | ❌ | ❌ | ✅ | ❌ | ✅ |
+| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| M-CTC-T | ❌ | ❌ | ✅ | ❌ | ❌ |
+| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
+| MarkupLM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Mask2Former | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MaskFormerSwin | ❌ | ❌ | ❌ | ❌ | ❌ |
+| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MEGA | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Megatron-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MGP-STR | ✅ | ❌ | ✅ | ❌ | ❌ |
+| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MobileNetV1 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileNetV2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MVP | ✅ | ✅ | ✅ | ❌ | ❌ |
+| NAT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Nezha | ❌ | ❌ | ✅ | ❌ | ❌ |
+| NLLB-MOE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Nyströmformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OneFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| OpenLlama | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OPT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| OWL-ViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
+| PEGASUS-X | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Pix2Struct | ❌ | ❌ | ✅ | ❌ | ❌ |
+| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
+| REALM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ResNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RoBERTa-PreLayerNorm | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RoCBert | ✅ | ❌ | ✅ | ❌ | ❌ |
+| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RWKV | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SAM | ❌ | ❌ | ✅ | ✅ | ❌ |
+| SegFormer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
+| SpeechT5 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SwiftFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Swin Transformer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Swin Transformer V2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Swin2SR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SwitchTransformers | ❌ | ❌ | ✅ | ❌ | ❌ |
+| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Table Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Time Series Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TimeSformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Trajectory Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TVLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TVP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UPerNet | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VideoMAE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisionTextDualEncoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisualBERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ViT Hybrid | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
+| ViTMSN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
+| Wav2Vec2-Conformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Whisper | ✅ | ✅ | ✅ | ✅ | ✅ |
+| X-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| X-MOD | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XGLM | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| XLM-ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| YOLOS | ❌ | ❌ | ✅ | ❌ | ❌ |
+| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/_config.py b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/_config.py
new file mode 100644
index 0000000000000000000000000000000000000000..f49e4e4731965a504b8da443c2cd979638cd22bb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/_config.py
@@ -0,0 +1,14 @@
+# docstyle-ignore
+INSTALL_CONTENT = """
+# Transformers installation
+! pip install transformers datasets evaluate accelerate
+# To install from source instead of the last release, comment the command above and uncomment the following one.
+# ! pip install git+https://github.com/huggingface/transformers.git
+"""
+
+notebook_first_cells = [{"type": "code", "content": INSTALL_CONTENT}]
+black_avoid_patterns = {
+ "{processor_class}": "FakeProcessorClass",
+ "{model_class}": "FakeModelClass",
+ "{object_class}": "FakeObjectClass",
+}
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/_toctree.yml b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..d042168f7b9b693d92c0f85e2142ca1ec43e1236
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/_toctree.yml
@@ -0,0 +1,38 @@
+- sections:
+ - local: index
+ title: 🤗 Transformers
+ - local: quicktour
+ title: Tour rápido
+ - local: installation
+ title: Instalação
+ title: Início
+- sections:
+ - local: pipeline_tutorial
+ title: Pipelines para inferência
+ - local: training
+ title: Fine-tuning de um modelo pré-treinado
+ - local: accelerate
+ title: Treinamento distribuído com 🤗 Accelerate
+ title: Tutoriais
+- sections:
+ - local: fast_tokenizers
+ title: Usando os Tokenizers do 🤗 Tokenizers
+ - local: create_a_model
+ title: Criando uma arquitetura customizada
+ - local: custom_models
+ title: Compartilhando modelos customizados
+ - local: run_scripts
+ title: Treinamento a partir de um script
+ - local: converting_tensorflow_models
+ title: Convertendo checkpoints do TensorFlow para Pytorch
+ - local: serialization
+ title: Exportando modelos para ONNX
+ - sections:
+ - local: tasks/sequence_classification
+ title: Classificação de texto
+ - local: tasks/token_classification
+ title: Classificação de tokens
+ title: Fine-tuning para tarefas específicas
+ - local: multilingual
+ title: Modelos multilinguísticos para inferência
+ title: Guias práticos
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/accelerate.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/accelerate.md
new file mode 100644
index 0000000000000000000000000000000000000000..a4e346a2b4873ff475ff9c3e34ff75e276fb58a7
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/accelerate.md
@@ -0,0 +1,145 @@
+
+
+# Treinamento distribuído com o 🤗 Accelerate
+
+O paralelismo surgiu como uma estratégia para treinar modelos grandes em hardware limitado e aumentar a velocidade
+de treinamento em várias órdens de magnitude. Na Hugging Face criamos a biblioteca [🤗 Accelerate](https://huggingface.co/docs/accelerate)
+para ajudar os usuários a treinar modelos 🤗 Transformers com qualquer configuração distribuída, seja em uma máquina
+com múltiplos GPUs ou em múltiplos GPUs distribuidos entre muitas máquinas. Neste tutorial, você irá aprender como
+personalizar seu laço de treinamento de PyTorch para poder treinar em ambientes distribuídos.
+
+## Configuração
+
+De início, instale o 🤗 Accelerate:
+
+```bash
+pip install accelerate
+```
+
+Logo, devemos importar e criar um objeto [`Accelerator`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator).
+O `Accelerator` detectará automáticamente a configuração distribuída disponível e inicializará todos os
+componentes necessários para o treinamento. Não há necessidade portanto de especificar o dispositivo onde deve colocar seu modelo.
+
+```py
+>>> from accelerate import Accelerator
+
+>>> accelerator = Accelerator()
+```
+
+## Preparando a aceleração
+
+Passe todos os objetos relevantes ao treinamento para o método [`prepare`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator.prepare).
+Isto inclui os DataLoaders de treino e evaluação, um modelo e um otimizador:
+
+```py
+>>> train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
+... train_dataloader, eval_dataloader, model, optimizer
+... )
+```
+
+## Backward
+
+Por último, substitua o `loss.backward()` padrão em seu laço de treinamento com o método [`backward`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator.backward) do 🤗 Accelerate:
+
+```py
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... outputs = model(**batch)
+... loss = outputs.loss
+... accelerator.backward(loss)
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+Como se poder ver no seguinte código, só precisará adicionar quatro linhas de código ao seu laço de treinamento
+para habilitar o treinamento distribuído!
+
+```diff
++ from accelerate import Accelerator
+ from transformers import AdamW, AutoModelForSequenceClassification, get_scheduler
+
++ accelerator = Accelerator()
+
+ model = AutoModelForSequenceClassification.from_pretrained(checkpoint, num_labels=2)
+ optimizer = AdamW(model.parameters(), lr=3e-5)
+
+- device = torch.device("cuda") if torch.cuda.is_available() else torch.device("cpu")
+- model.to(device)
+
++ train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
++ train_dataloader, eval_dataloader, model, optimizer
++ )
+
+ num_epochs = 3
+ num_training_steps = num_epochs * len(train_dataloader)
+ lr_scheduler = get_scheduler(
+ "linear",
+ optimizer=optimizer,
+ num_warmup_steps=0,
+ num_training_steps=num_training_steps
+ )
+
+ progress_bar = tqdm(range(num_training_steps))
+
+ model.train()
+ for epoch in range(num_epochs):
+ for batch in train_dataloader:
+- batch = {k: v.to(device) for k, v in batch.items()}
+ outputs = model(**batch)
+ loss = outputs.loss
+- loss.backward()
++ accelerator.backward(loss)
+
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ progress_bar.update(1)
+```
+
+## Treinamento
+
+Quando tiver adicionado as linhas de código relevantes, inicie o treinamento por um script ou notebook como o Colab.
+
+### Treinamento em um Script
+
+Se estiver rodando seu treinamento em um Script, execute o seguinte comando para criar e guardar um arquivo de configuração:
+
+```bash
+accelerate config
+```
+
+Comece o treinamento com:
+
+```bash
+accelerate launch train.py
+```
+
+### Treinamento em um Notebook
+
+O 🤗 Accelerate pode rodar em um notebook, por exemplo, se estiver planejando usar as TPUs do Google Colab.
+Encapsule o código responsável pelo treinamento de uma função e passe-o ao `notebook_launcher`:
+
+```py
+>>> from accelerate import notebook_launcher
+
+>>> notebook_launcher(training_function)
+```
+
+Para obter mais informações sobre o 🤗 Accelerate e suas numerosas funções, consulte a [documentación](https://huggingface.co/docs/accelerate/index).
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/converting_tensorflow_models.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/converting_tensorflow_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..63e926d4dcfe6c2a8c65c112a37b0a42f77786d5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/converting_tensorflow_models.md
@@ -0,0 +1,152 @@
+
+
+# Convertendo checkpoints do TensorFlow para Pytorch
+
+Uma interface de linha de comando é fornecida para converter os checkpoints originais Bert/GPT/GPT-2/Transformer-XL/XLNet/XLM em modelos
+que podem ser carregados usando os métodos `from_pretrained` da biblioteca.
+
+
+
+A partir da versão 2.3.0 o script de conversão agora faz parte do transformers CLI (**transformers-cli**) disponível em qualquer instalação
+transformers >= 2.3.0.
+
+A documentação abaixo reflete o formato do comando **transformers-cli convert**.
+
+
+
+## BERT
+
+Você pode converter qualquer checkpoint do BERT em TensorFlow (em particular [os modelos pré-treinados lançados pelo Google](https://github.com/google-research/bert#pre-trained-models)) em um arquivo PyTorch usando um
+[convert_bert_original_tf_checkpoint_to_pytorch.py](https://github.com/huggingface/transformers/tree/main/src/transformers/models/bert/convert_bert_original_tf_checkpoint_to_pytorch.py) script.
+
+Esta Interface de Linha de Comando (CLI) recebe como entrada um checkpoint do TensorFlow (três arquivos começando com `bert_model.ckpt`) e o
+arquivo de configuração (`bert_config.json`), e então cria um modelo PyTorch para esta configuração, carrega os pesos
+do checkpoint do TensorFlow no modelo PyTorch e salva o modelo resultante em um arquivo PyTorch que pode
+ser importado usando `from_pretrained()` (veja o exemplo em [quicktour](quicktour) , [run_glue.py](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-classification/run_glue.py) ).
+
+Você só precisa executar este script de conversão **uma vez** para obter um modelo PyTorch. Você pode então desconsiderar o checkpoint em
+ TensorFlow (os três arquivos começando com `bert_model.ckpt`), mas certifique-se de manter o arquivo de configuração (\
+`bert_config.json`) e o arquivo de vocabulário (`vocab.txt`), pois eles também são necessários para o modelo PyTorch.
+
+Para executar este script de conversão específico, você precisará ter o TensorFlow e o PyTorch instalados (`pip install tensorflow`). O resto do repositório requer apenas o PyTorch.
+
+Aqui está um exemplo do processo de conversão para um modelo `BERT-Base Uncased` pré-treinado:
+
+```bash
+export BERT_BASE_DIR=/path/to/bert/uncased_L-12_H-768_A-12
+
+transformers-cli convert --model_type bert \
+ --tf_checkpoint $BERT_BASE_DIR/bert_model.ckpt \
+ --config $BERT_BASE_DIR/bert_config.json \
+ --pytorch_dump_output $BERT_BASE_DIR/pytorch_model.bin
+```
+
+Você pode baixar os modelos pré-treinados do Google para a conversão [aqui](https://github.com/google-research/bert#pre-trained-models).
+
+## ALBERT
+
+Converta os checkpoints do modelo ALBERT em TensorFlow para PyTorch usando o
+[convert_albert_original_tf_checkpoint_to_pytorch.py](https://github.com/huggingface/transformers/tree/main/src/transformers/models/albert/convert_albert_original_tf_checkpoint_to_pytorch.py) script.
+
+A Interface de Linha de Comando (CLI) recebe como entrada um checkpoint do TensorFlow (três arquivos começando com `model.ckpt-best`) e o
+arquivo de configuração (`albert_config.json`), então cria e salva um modelo PyTorch. Para executar esta conversão, você
+precisa ter o TensorFlow e o PyTorch instalados.
+
+Aqui está um exemplo do processo de conversão para o modelo `ALBERT Base` pré-treinado:
+
+```bash
+export ALBERT_BASE_DIR=/path/to/albert/albert_base
+
+transformers-cli convert --model_type albert \
+ --tf_checkpoint $ALBERT_BASE_DIR/model.ckpt-best \
+ --config $ALBERT_BASE_DIR/albert_config.json \
+ --pytorch_dump_output $ALBERT_BASE_DIR/pytorch_model.bin
+```
+
+Você pode baixar os modelos pré-treinados do Google para a conversão [aqui](https://github.com/google-research/albert#pre-trained-models).
+
+## OpenAI GPT
+
+Aqui está um exemplo do processo de conversão para um modelo OpenAI GPT pré-treinado, supondo que seu checkpoint NumPy
+foi salvo com o mesmo formato do modelo pré-treinado OpenAI (veja [aqui](https://github.com/openai/finetune-transformer-lm)\
+)
+
+```bash
+export OPENAI_GPT_CHECKPOINT_FOLDER_PATH=/path/to/openai/pretrained/numpy/weights
+
+transformers-cli convert --model_type gpt \
+ --tf_checkpoint $OPENAI_GPT_CHECKPOINT_FOLDER_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT \
+ [--config OPENAI_GPT_CONFIG] \
+ [--finetuning_task_name OPENAI_GPT_FINETUNED_TASK] \
+```
+
+## OpenAI GPT-2
+
+Aqui está um exemplo do processo de conversão para um modelo OpenAI GPT-2 pré-treinado (consulte [aqui](https://github.com/openai/gpt-2))
+
+```bash
+export OPENAI_GPT2_CHECKPOINT_PATH=/path/to/openai-community/gpt2/pretrained/weights
+
+transformers-cli convert --model_type gpt2 \
+ --tf_checkpoint $OPENAI_GPT2_CHECKPOINT_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT \
+ [--config OPENAI_GPT2_CONFIG] \
+ [--finetuning_task_name OPENAI_GPT2_FINETUNED_TASK]
+```
+
+## XLNet
+
+Aqui está um exemplo do processo de conversão para um modelo XLNet pré-treinado:
+
+```bash
+export TRANSFO_XL_CHECKPOINT_PATH=/path/to/xlnet/checkpoint
+export TRANSFO_XL_CONFIG_PATH=/path/to/xlnet/config
+
+transformers-cli convert --model_type xlnet \
+ --tf_checkpoint $TRANSFO_XL_CHECKPOINT_PATH \
+ --config $TRANSFO_XL_CONFIG_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT \
+ [--finetuning_task_name XLNET_FINETUNED_TASK] \
+```
+
+## XLM
+
+Aqui está um exemplo do processo de conversão para um modelo XLM pré-treinado:
+
+```bash
+export XLM_CHECKPOINT_PATH=/path/to/xlm/checkpoint
+
+transformers-cli convert --model_type xlm \
+ --tf_checkpoint $XLM_CHECKPOINT_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT
+ [--config XML_CONFIG] \
+ [--finetuning_task_name XML_FINETUNED_TASK]
+```
+
+## T5
+
+Aqui está um exemplo do processo de conversão para um modelo T5 pré-treinado:
+
+```bash
+export T5=/path/to/t5/uncased_L-12_H-768_A-12
+
+transformers-cli convert --model_type t5 \
+ --tf_checkpoint $T5/t5_model.ckpt \
+ --config $T5/t5_config.json \
+ --pytorch_dump_output $T5/pytorch_model.bin
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/create_a_model.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/create_a_model.md
new file mode 100644
index 0000000000000000000000000000000000000000..dd71963236f4fa9eb37add6c04ebd4b967069175
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/create_a_model.md
@@ -0,0 +1,359 @@
+
+
+# Criar uma arquitetura customizada
+
+Uma [`AutoClass`](model_doc/auto) automaticamente infere a arquitetura do modelo e baixa configurações e pesos pré-treinados. Geralmente, nós recomendamos usar uma `AutoClass` para produzir um código independente de checkpoints. Mas usuários que querem mais contole sobre parâmetros específicos do modelo pode criar um modelo customizado 🤗 Transformers a partir de algumas classes bases. Isso pode ser particulamente útil para alguém que está interessado em estudar, treinar ou fazer experimentos com um modelo 🤗 Transformers. Nesse tutorial, será explicado como criar um modelo customizado sem uma `AutoClass`. Aprenda como:
+
+- Carregar e customizar a configuração de um modelo.
+- Criar a arquitetura de um modelo.
+- Criar um tokenizer rápido e devagar para textos.
+- Criar extrator de features para tarefas envolvendo audio e imagem.
+- Criar um processador para tarefas multimodais.
+
+## configuration
+
+A [configuration](main_classes/configuration) refere-se a atributos específicos de um modelo. Cada configuração de modelo tem atributos diferentes; por exemplo, todos modelo de PLN possuem os atributos `hidden_size`, `num_attention_heads`, `num_hidden_layers` e `vocab_size` em comum. Esse atributos especificam o numero de 'attention heads' ou 'hidden layers' para construir um modelo.
+
+Dê uma olhada a mais em [DistilBERT](model_doc/distilbert) acessando [`DistilBertConfig`] para observar esses atributos:
+
+```py
+>>> from transformers import DistilBertConfig
+
+>>> config = DistilBertConfig()
+>>> print(config)
+DistilBertConfig {
+ "activation": "gelu",
+ "attention_dropout": 0.1,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+[`DistilBertConfig`] mostra todos os atributos padrões usados para construir um [`DistilBertModel`] base. Todos atributos são customizáveis, o que cria espaço para experimentos. Por exemplo, você pode customizar um modelo padrão para:
+
+- Tentar uma função de ativação diferente com o parâmetro `activation`.
+- Usar uma taxa de desistência maior para as probabilidades de 'attention' com o parâmetro `attention_dropout`.
+
+```py
+>>> my_config = DistilBertConfig(activation="relu", attention_dropout=0.4)
+>>> print(my_config)
+DistilBertConfig {
+ "activation": "relu",
+ "attention_dropout": 0.4,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+Atributos de um modelo pré-treinado podem ser modificados na função [`~PretrainedConfig.from_pretrained`]:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("distilbert/distilbert-base-uncased", activation="relu", attention_dropout=0.4)
+```
+
+Uma vez que você está satisfeito com as configurações do seu modelo, você consegue salvar elas com [`~PretrainedConfig.save_pretrained`]. Seu arquivo de configurações está salvo como um arquivo JSON no diretório especificado:
+
+```py
+>>> my_config.save_pretrained(save_directory="./your_model_save_path")
+```
+
+Para reusar o arquivo de configurações, carregue com [`~PretrainedConfig.from_pretrained`]:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+```
+
+
+
+Você pode também salvar seu arquivo de configurações como um dicionário ou até mesmo com a diferença entre as seus atributos de configuração customizados e os atributos de configuração padrões! Olhe a documentação [configuration](main_classes/configuration) para mais detalhes.
+
+
+
+## Modelo
+
+O próximo passo é criar um [model](main_classes/models). O modelo - também vagamente referido como arquitetura - define o que cada camada está fazendo e quais operações estão acontecendo. Atributos como `num_hidden_layers` das configurações são utilizados para definir a arquitetura. Todo modelo compartilha a classe base [`PreTrainedModel`] e alguns métodos em comum como redimensionar o tamanho dos embeddings de entrada e podar as 'self-attention heads'. Além disso, todos os modelos também são subclasses de [`torch.nn.Module`](https://pytorch.org/docs/stable/generated/torch.nn.Module.html), [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) ou [`flax.linen.Module`](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html). Isso significa que os modelos são compatíveis com cada respectivo uso de framework.
+
+
+
+Carregar seus atributos de configuração customizados em um modelo:
+
+```py
+>>> from transformers import DistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+>>> model = DistilBertModel(my_config)
+```
+
+Isso cria um modelo com valores aleatórios ao invés de pré-treinar os pesos. Você não irá conseguir usar usar esse modelo para nada útil ainda, até você treinar ele. Treino é um processo caro e demorado. Geralmente é melhor utilizar um modelo pré-treinado para obter melhores resultados mais rápido, enquanto usa apenas uma fração dos recursos necessários para treinar.
+
+Criar um modelo pré-treinado com [`~PreTrainedModel.from_pretrained`]:
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Quando você carregar os pesos pré-treinados, a configuração padrão do modelo é automaticamente carregada se o modelo é provido pelo 🤗 Transformers. No entanto, você ainda consegue mudar - alguns ou todos - os atributos padrões de configuração do modelo com os seus próprio atributos, se você preferir:
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+Carregar os seus próprios atributos padrões de contiguração no modelo:
+
+```py
+>>> from transformers import TFDistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+>>> tf_model = TFDistilBertModel(my_config)
+```
+
+Isso cria um modelo com valores aleatórios ao invés de pré-treinar os pesos. Você não irá conseguir usar usar esse modelo para nada útil ainda, até você treinar ele. Treino é um processo caro e demorado. Geralmente é melhor utilizar um modelo pré-treinado para obter melhores resultados mais rápido, enquanto usa apenas uma fração dos recursos necessários para treinar.
+
+Criar um modelo pré-treinado com [`~TFPreTrainedModel.from_pretrained`]:
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Quando você carregar os pesos pré-treinados, a configuração padrão do modelo é automaticamente carregada se o modelo é provido pelo 🤗 Transformers. No entanto, você ainda consegue mudar - alguns ou todos - os atributos padrões de configuração do modelo com os seus próprio atributos, se você preferir:
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+
+### Heads do modelo
+
+Neste ponto, você tem um modelo básico do DistilBERT que gera os *estados ocultos*. Os estados ocultos são passados como entrada para a head do moelo para produzir a saída final. 🤗 Transformers fornece uma head de modelo diferente para cada tarefa desde que o modelo suporte essa tarefa (por exemplo, você não consegue utilizar o modelo DistilBERT para uma tarefa de 'sequence-to-sequence' como tradução).
+
+
+
+Por exemplo, [`DistilBertForSequenceClassification`] é um modelo DistilBERT base com uma head de classificação de sequência. A head de calssificação de sequência é uma camada linear no topo das saídas agrupadas.
+
+```py
+>>> from transformers import DistilBertForSequenceClassification
+
+>>> model = DistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Reutilize facilmente esse ponto de parada para outra tarefe mudando para uma head de modelo diferente. Para uma tarefe de responder questões, você usaria a head do modelo [`DistilBertForQuestionAnswering`]. A head de responder questões é similar com a de classificação de sequências exceto o fato de que ela é uma camada no topo dos estados das saídas ocultas.
+
+```py
+>>> from transformers import DistilBertForQuestionAnswering
+
+>>> model = DistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+Por exemplo, [`TFDistilBertForSequenceClassification`] é um modelo DistilBERT base com uma head de classificação de sequência. A head de calssificação de sequência é uma camada linear no topo das saídas agrupadas.
+
+```py
+>>> from transformers import TFDistilBertForSequenceClassification
+
+>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Reutilize facilmente esse ponto de parada para outra tarefe mudando para uma head de modelo diferente. Para uma tarefe de responder questões, você usaria a head do modelo [`TFDistilBertForQuestionAnswering`]. A head de responder questões é similar com a de classificação de sequências exceto o fato de que ela é uma camada no topo dos estados das saídas ocultas.
+
+```py
+>>> from transformers import TFDistilBertForQuestionAnswering
+
+>>> tf_model = TFDistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+## Tokenizer
+
+A útlima classe base que você precisa antes de usar um modelo para dados textuais é a [tokenizer](main_classes/tokenizer) para converter textos originais para tensores. Existem dois tipos de tokenizers que você pode usar com 🤗 Transformers:
+
+- [`PreTrainedTokenizer`]: uma implementação em Python de um tokenizer.
+- [`PreTrainedTokenizerFast`]: um tokenizer da nossa biblioteca [🤗 Tokenizer](https://huggingface.co/docs/tokenizers/python/latest/) baseada em Rust. Esse tipo de tokenizer é significantemente mais rapido - especialmente durante tokenization de codificação - devido a implementação em Rust. O tokenizer rápido tambem oferece métodos adicionais como *offset mapping* que mapeia tokens para suar palavras ou caracteres originais.
+
+Os dois tokenizers suporta métodos comuns como os de codificar e decodificar, adicionar novos tokens, e gerenciar tokens especiais.
+
+
+
+Nem todo modelo suporta um 'fast tokenizer'. De uma olhada aqui [table](index#supported-frameworks) pra checar se um modelo suporta 'fast tokenizer'.
+
+
+
+Se você treinou seu prórpio tokenizer, você pode criar um a partir do seu arquivo *vocabulary*:
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> my_tokenizer = DistilBertTokenizer(vocab_file="my_vocab_file.txt", do_lower_case=False, padding_side="left")
+```
+
+É importante lembrar que o vocabulário de um tokenizer customizado será diferente de um vocabulário gerado pelo tokenizer de um modelo pré treinado. Você precisa usar o vocabulário de um modelo pré treinado se você estiver usando um modelo pré treinado, caso contrário as entradas não farão sentido. Criando um tokenizer com um vocabulário de um modelo pré treinado com a classe [`DistilBertTokenizer`]:
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> slow_tokenizer = DistilBertTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Criando um 'fast tokenizer' com a classe [`DistilBertTokenizerFast`]:
+
+```py
+>>> from transformers import DistilBertTokenizerFast
+
+>>> fast_tokenizer = DistilBertTokenizerFast.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+Pos padrão, [`AutoTokenizer`] tentará carregar um 'fast tokenizer'. Você pode disabilitar esse comportamento colocando `use_fast=False` no `from_pretrained`.
+
+
+
+## Extrator de features
+
+Um extrator de features processa entradas de imagem ou áudio. Ele herda da classe base [`~feature_extraction_utils.FeatureExtractionMixin`], e pode também herdar da classe [`ImageFeatureExtractionMixin`] para processamento de features de imagem ou da classe [`SequenceFeatureExtractor`] para processamento de entradas de áudio.
+
+Dependendo do que você está trabalhando em um audio ou uma tarefa de visão, crie um estrator de features associado com o modelo que você está usando. Por exemplo, crie um [`ViTFeatureExtractor`] padrão se você estiver usando [ViT](model_doc/vit) para classificação de imagens:
+
+```py
+>>> from transformers import ViTFeatureExtractor
+
+>>> vit_extractor = ViTFeatureExtractor()
+>>> print(vit_extractor)
+ViTFeatureExtractor {
+ "do_normalize": true,
+ "do_resize": true,
+ "feature_extractor_type": "ViTFeatureExtractor",
+ "image_mean": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": 2,
+ "size": 224
+}
+```
+
+
+
+Se você não estiver procurando por nenhuma customização, apenas use o método `from_pretrained` para carregar parâmetros do modelo de extrator de features padrão.
+
+
+
+Modifique qualquer parâmetro dentre os [`ViTFeatureExtractor`] para criar seu extrator de features customizado.
+
+```py
+>>> from transformers import ViTFeatureExtractor
+
+>>> my_vit_extractor = ViTFeatureExtractor(resample="PIL.Image.BOX", do_normalize=False, image_mean=[0.3, 0.3, 0.3])
+>>> print(my_vit_extractor)
+ViTFeatureExtractor {
+ "do_normalize": false,
+ "do_resize": true,
+ "feature_extractor_type": "ViTFeatureExtractor",
+ "image_mean": [
+ 0.3,
+ 0.3,
+ 0.3
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": "PIL.Image.BOX",
+ "size": 224
+}
+```
+
+Para entradas de áutio, você pode criar um [`Wav2Vec2FeatureExtractor`] e customizar os parâmetros de uma forma similar:
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> w2v2_extractor = Wav2Vec2FeatureExtractor()
+>>> print(w2v2_extractor)
+Wav2Vec2FeatureExtractor {
+ "do_normalize": true,
+ "feature_extractor_type": "Wav2Vec2FeatureExtractor",
+ "feature_size": 1,
+ "padding_side": "right",
+ "padding_value": 0.0,
+ "return_attention_mask": false,
+ "sampling_rate": 16000
+}
+```
+
+## Processor
+
+Para modelos que suportam tarefas multimodais, 🤗 Transformers oferece uma classe processadora que convenientemente cobre um extrator de features e tokenizer dentro de um único objeto. Por exemplo, vamos usar o [`Wav2Vec2Processor`] para uma tarefa de reconhecimento de fala automática (ASR). ASR transcreve áudio para texto, então você irá precisar de um extrator de um features e um tokenizer.
+
+Crie um extrator de features para lidar com as entradas de áudio.
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> feature_extractor = Wav2Vec2FeatureExtractor(padding_value=1.0, do_normalize=True)
+```
+
+Crie um tokenizer para lidar com a entrada de textos:
+
+```py
+>>> from transformers import Wav2Vec2CTCTokenizer
+
+>>> tokenizer = Wav2Vec2CTCTokenizer(vocab_file="my_vocab_file.txt")
+```
+
+Combine o extrator de features e o tokenizer no [`Wav2Vec2Processor`]:
+
+```py
+>>> from transformers import Wav2Vec2Processor
+
+>>> processor = Wav2Vec2Processor(feature_extractor=feature_extractor, tokenizer=tokenizer)
+```
+
+Com duas classes básicas - configuração e modelo - e um preprocessamento de classe adicional (tokenizer, extrator de features, ou processador), você pode criar qualquer modelo que suportado por 🤗 Transformers. Qualquer uma dessas classes base são configuráveis, te permitindo usar os atributos específicos que você queira. Você pode facilmente preparar um modelo para treinamento ou modificar um modelo pré-treinado com poucas mudanças.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/custom_models.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/custom_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..27633f9d1bb238751ab0e49a254c0bec28ae4013
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/custom_models.md
@@ -0,0 +1,358 @@
+
+
+# Compartilhando modelos customizados
+
+A biblioteca 🤗 Transformers foi projetada para ser facilmente extensível. Cada modelo é totalmente codificado em uma determinada subpasta
+do repositório sem abstração, para que você possa copiar facilmente um arquivo de modelagem e ajustá-lo às suas necessidades.
+
+Se você estiver escrevendo um modelo totalmente novo, pode ser mais fácil começar do zero. Neste tutorial, mostraremos
+como escrever um modelo customizado e sua configuração para que possa ser usado com Transformers, e como você pode compartilhá-lo
+com a comunidade (com o código em que se baseia) para que qualquer pessoa possa usá-lo, mesmo se não estiver presente na biblioteca 🤗 Transformers.
+
+Ilustraremos tudo isso em um modelo ResNet, envolvendo a classe ResNet do
+[biblioteca timm](https://github.com/rwightman/pytorch-image-models) em um [`PreTrainedModel`].
+
+## Escrevendo uma configuração customizada
+
+Antes de mergulharmos no modelo, vamos primeiro escrever sua configuração. A configuração de um modelo é um objeto que
+terá todas as informações necessárias para construir o modelo. Como veremos na próxima seção, o modelo só pode
+ter um `config` para ser inicializado, então realmente precisamos que esse objeto seja o mais completo possível.
+
+Em nosso exemplo, pegaremos alguns argumentos da classe ResNet que podemos querer ajustar. Diferentes
+configurações nos dará os diferentes tipos de ResNets que são possíveis. Em seguida, apenas armazenamos esses argumentos,
+após verificar a validade de alguns deles.
+
+```python
+from transformers import PretrainedConfig
+from typing import List
+
+
+class ResnetConfig(PretrainedConfig):
+ model_type = "resnet"
+
+ def __init__(
+ self,
+ block_type="bottleneck",
+ layers: List[int] = [3, 4, 6, 3],
+ num_classes: int = 1000,
+ input_channels: int = 3,
+ cardinality: int = 1,
+ base_width: int = 64,
+ stem_width: int = 64,
+ stem_type: str = "",
+ avg_down: bool = False,
+ **kwargs,
+ ):
+ if block_type not in ["basic", "bottleneck"]:
+ raise ValueError(f"`block_type` must be 'basic' or bottleneck', got {block_type}.")
+ if stem_type not in ["", "deep", "deep-tiered"]:
+ raise ValueError(f"`stem_type` must be '', 'deep' or 'deep-tiered', got {stem_type}.")
+
+ self.block_type = block_type
+ self.layers = layers
+ self.num_classes = num_classes
+ self.input_channels = input_channels
+ self.cardinality = cardinality
+ self.base_width = base_width
+ self.stem_width = stem_width
+ self.stem_type = stem_type
+ self.avg_down = avg_down
+ super().__init__(**kwargs)
+```
+
+As três coisas importantes a serem lembradas ao escrever sua própria configuração são:
+- você tem que herdar de `PretrainedConfig`,
+- o `__init__` do seu `PretrainedConfig` deve aceitar quaisquer kwargs,
+- esses `kwargs` precisam ser passados para a superclasse `__init__`.
+
+A herança é para garantir que você obtenha todas as funcionalidades da biblioteca 🤗 Transformers, enquanto as outras duas
+restrições vêm do fato de um `PretrainedConfig` ter mais campos do que os que você está configurando. Ao recarregar um
+config com o método `from_pretrained`, esses campos precisam ser aceitos pelo seu config e então enviados para a
+superclasse.
+
+Definir um `model_type` para sua configuração (aqui `model_type="resnet"`) não é obrigatório, a menos que você queira
+registrar seu modelo com as classes automáticas (veja a última seção).
+
+Com isso feito, você pode facilmente criar e salvar sua configuração como faria com qualquer outra configuração de modelo da
+biblioteca. Aqui está como podemos criar uma configuração resnet50d e salvá-la:
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d_config.save_pretrained("custom-resnet")
+```
+
+Isso salvará um arquivo chamado `config.json` dentro da pasta `custom-resnet`. Você pode então recarregar sua configuração com o
+método `from_pretrained`:
+
+```py
+resnet50d_config = ResnetConfig.from_pretrained("custom-resnet")
+```
+
+Você também pode usar qualquer outro método da classe [`PretrainedConfig`], como [`~PretrainedConfig.push_to_hub`] para
+carregar diretamente sua configuração para o Hub.
+
+## Escrevendo um modelo customizado
+
+Agora que temos nossa configuração ResNet, podemos continuar escrevendo o modelo. Na verdade, escreveremos dois: um que
+extrai os recursos ocultos de um lote de imagens (como [`BertModel`]) e um que é adequado para classificação de imagem
+(como [`BertForSequenceClassification`]).
+
+Como mencionamos antes, escreveremos apenas um wrapper solto do modelo para mantê-lo simples para este exemplo. A única
+coisa que precisamos fazer antes de escrever esta classe é um mapa entre os tipos de bloco e as classes de bloco reais. Então o
+modelo é definido a partir da configuração passando tudo para a classe `ResNet`:
+
+```py
+from transformers import PreTrainedModel
+from timm.models.resnet import BasicBlock, Bottleneck, ResNet
+from .configuration_resnet import ResnetConfig
+
+
+BLOCK_MAPPING = {"basic": BasicBlock, "bottleneck": Bottleneck}
+
+
+class ResnetModel(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor):
+ return self.model.forward_features(tensor)
+```
+
+Para o modelo que irá classificar as imagens, vamos apenas alterar o método forward:
+
+```py
+import torch
+
+
+class ResnetModelForImageClassification(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor, labels=None):
+ logits = self.model(tensor)
+ if labels is not None:
+ loss = torch.nn.functional.cross_entropy(logits, labels)
+ return {"loss": loss, "logits": logits}
+ return {"logits": logits}
+```
+
+Em ambos os casos, observe como herdamos de `PreTrainedModel` e chamamos a inicialização da superclasse com o `config`
+(um pouco parecido quando você escreve um `torch.nn.Module`). A linha que define o `config_class` não é obrigatória, a menos que
+você deseje registrar seu modelo com as classes automáticas (consulte a última seção).
+
+
+
+Se o seu modelo for muito semelhante a um modelo dentro da biblioteca, você poderá reutilizar a mesma configuração desse modelo.
+
+
+
+Você pode fazer com que seu modelo retorne o que você quiser,porém retornando um dicionário como fizemos para
+`ResnetModelForImageClassification`, com a função de perda incluída quando os rótulos são passados, vai tornar seu modelo diretamente
+utilizável dentro da classe [`Trainer`]. Você pode usar outro formato de saída, desde que esteja planejando usar seu próprio
+laço de treinamento ou outra biblioteca para treinamento.
+
+Agora que temos nossa classe do modelo, vamos criar uma:
+
+```py
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+```
+
+Novamente, você pode usar qualquer um dos métodos do [`PreTrainedModel`], como [`~PreTrainedModel.save_pretrained`] ou
+[`~PreTrainedModel.push_to_hub`]. Usaremos o segundo na próxima seção e veremos como enviar os pesos e
+o código do nosso modelo. Mas primeiro, vamos carregar alguns pesos pré-treinados dentro do nosso modelo.
+
+Em seu próprio caso de uso, você provavelmente estará treinando seu modelo customizado em seus próprios dados. Para este tutorial ser rápido,
+usaremos a versão pré-treinada do resnet50d. Como nosso modelo é apenas um wrapper em torno dele, será
+fácil de transferir esses pesos:
+
+```py
+import timm
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+Agora vamos ver como ter certeza de que quando fazemos [`~PreTrainedModel.save_pretrained`] ou [`~PreTrainedModel.push_to_hub`], o
+código do modelo é salvo.
+
+## Enviando o código para o Hub
+
+
+
+Esta API é experimental e pode ter algumas pequenas alterações nas próximas versões.
+
+
+
+Primeiro, certifique-se de que seu modelo esteja totalmente definido em um arquivo `.py`. Ele pode contar com importações relativas para alguns outros arquivos
+desde que todos os arquivos estejam no mesmo diretório (ainda não suportamos submódulos para este recurso). Para o nosso exemplo,
+vamos definir um arquivo `modeling_resnet.py` e um arquivo `configuration_resnet.py` em uma pasta no
+diretório de trabalho atual chamado `resnet_model`. O arquivo de configuração contém o código para `ResnetConfig` e o arquivo de modelagem
+contém o código do `ResnetModel` e `ResnetModelForImageClassification`.
+
+```
+.
+└── resnet_model
+ ├── __init__.py
+ ├── configuration_resnet.py
+ └── modeling_resnet.py
+```
+
+O `__init__.py` pode estar vazio, apenas está lá para que o Python detecte que o `resnet_model` possa ser usado como um módulo.
+
+
+
+Se estiver copiando arquivos de modelagem da biblioteca, você precisará substituir todas as importações relativas na parte superior do arquivo
+para importar do pacote `transformers`.
+
+
+
+Observe que você pode reutilizar (ou subclasse) uma configuração/modelo existente.
+
+Para compartilhar seu modelo com a comunidade, siga estas etapas: primeiro importe o modelo ResNet e a configuração do
+arquivos criados:
+
+```py
+from resnet_model.configuration_resnet import ResnetConfig
+from resnet_model.modeling_resnet import ResnetModel, ResnetModelForImageClassification
+```
+
+Então você tem que dizer à biblioteca que deseja copiar os arquivos de código desses objetos ao usar o `save_pretrained`
+e registrá-los corretamente com uma determinada classe automáticas (especialmente para modelos), basta executar:
+
+```py
+ResnetConfig.register_for_auto_class()
+ResnetModel.register_for_auto_class("AutoModel")
+ResnetModelForImageClassification.register_for_auto_class("AutoModelForImageClassification")
+```
+
+Observe que não há necessidade de especificar uma classe automática para a configuração (há apenas uma classe automática,
+[`AutoConfig`]), mas é diferente para os modelos. Seu modelo customizado pode ser adequado para muitas tarefas diferentes, então você
+tem que especificar qual das classes automáticas é a correta para o seu modelo.
+
+Em seguida, vamos criar a configuração e os modelos como fizemos antes:
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+Agora para enviar o modelo para o Hub, certifique-se de estar logado. Ou execute no seu terminal:
+
+```bash
+huggingface-cli login
+```
+
+ou a partir do notebook:
+
+```py
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+Você pode então enviar para seu próprio namespace (ou uma organização da qual você é membro) assim:
+
+
+```py
+resnet50d.push_to_hub("custom-resnet50d")
+```
+
+Além dos pesos do modelo e da configuração no formato json, isso também copiou o modelo e
+configuração `.py` na pasta `custom-resnet50d` e carregou o resultado para o Hub. Você pode conferir o resultado
+neste [repositório de modelos](https://huggingface.co/sgugger/custom-resnet50d).
+
+Consulte o [tutorial de compartilhamento](model_sharing) para obter mais informações sobre o método push_to_hub.
+
+## Usando um modelo com código customizado
+
+Você pode usar qualquer configuração, modelo ou tokenizador com arquivos de código customizados em seu repositório com as classes automáticas e
+o método `from_pretrained`. Todos os arquivos e códigos carregados no Hub são verificados quanto a malware (consulte a documentação de [Segurança do Hub](https://huggingface.co/docs/hub/security#malware-scanning) para obter mais informações), mas você ainda deve
+revisar o código do modelo e o autor para evitar a execução de código malicioso em sua máquina. Defina `trust_remote_code=True` para usar
+um modelo com código customizado:
+
+```py
+from transformers import AutoModelForImageClassification
+
+model = AutoModelForImageClassification.from_pretrained("sgugger/custom-resnet50d", trust_remote_code=True)
+```
+
+Também é fortemente recomendado passar um hash de confirmação como uma `revisão` para garantir que o autor dos modelos não
+atualize o código com novas linhas maliciosas (a menos que você confie totalmente nos autores dos modelos).
+
+
+```py
+commit_hash = "ed94a7c6247d8aedce4647f00f20de6875b5b292"
+model = AutoModelForImageClassification.from_pretrained(
+ "sgugger/custom-resnet50d", trust_remote_code=True, revision=commit_hash
+)
+```
+
+Observe que ao navegar no histórico de commits do repositório do modelo no Hub, há um botão para copiar facilmente o commit
+hash de qualquer commit.
+
+## Registrando um modelo com código customizado para as classes automáticas
+
+Se você estiver escrevendo uma biblioteca que estende 🤗 Transformers, talvez queira estender as classes automáticas para incluir seus próprios
+modelos. Isso é diferente de enviar o código para o Hub no sentido de que os usuários precisarão importar sua biblioteca para
+obter os modelos customizados (ao contrário de baixar automaticamente o código do modelo do Hub).
+
+Desde que sua configuração tenha um atributo `model_type` diferente dos tipos de modelo existentes e que as classes do seu modelo
+tenha os atributos `config_class` corretos, você pode simplesmente adicioná-los às classes automáticas assim:
+
+```py
+from transformers import AutoConfig, AutoModel, AutoModelForImageClassification
+
+AutoConfig.register("resnet", ResnetConfig)
+AutoModel.register(ResnetConfig, ResnetModel)
+AutoModelForImageClassification.register(ResnetConfig, ResnetModelForImageClassification)
+```
+
+Observe que o primeiro argumento usado ao registrar sua configuração customizada para [`AutoConfig`] precisa corresponder ao `model_type`
+de sua configuração customizada. E o primeiro argumento usado ao registrar seus modelos customizados, para qualquer necessidade de classe de modelo automático
+deve corresponder ao `config_class` desses modelos.
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/fast_tokenizers.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/fast_tokenizers.md
new file mode 100644
index 0000000000000000000000000000000000000000..ea1da8a61571f1a4969e1b7751de08a8b0ca40ea
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/fast_tokenizers.md
@@ -0,0 +1,66 @@
+
+
+# Usando os Tokenizers do 🤗 Tokenizers
+
+O [`PreTrainedTokenizerFast`] depende da biblioteca [🤗 Tokenizers](https://huggingface.co/docs/tokenizers). O Tokenizer obtido da biblioteca 🤗 Tokenizers pode ser carregado facilmente pelo 🤗 Transformers.
+
+Antes de entrar nos detalhes, vamos começar criando um tokenizer fictício em algumas linhas:
+
+```python
+>>> from tokenizers import Tokenizer
+>>> from tokenizers.models import BPE
+>>> from tokenizers.trainers import BpeTrainer
+>>> from tokenizers.pre_tokenizers import Whitespace
+
+>>> tokenizer = Tokenizer(BPE(unk_token="[UNK]"))
+>>> trainer = BpeTrainer(special_tokens=["[UNK]", "[CLS]", "[SEP]", "[PAD]", "[MASK]"])
+
+>>> tokenizer.pre_tokenizer = Whitespace()
+>>> files = [...]
+>>> tokenizer.train(files, trainer)
+```
+
+Agora temos um tokenizer treinado nos arquivos que foram definidos. Nós podemos continuar usando nessa execução ou salvar em um arquivo JSON para re-utilizar no futuro.
+
+## Carregando diretamente de um objeto tokenizer
+
+Vamos ver como aproveitar esse objeto tokenizer na biblioteca 🤗 Transformers. A classe [`PreTrainedTokenizerFast`] permite uma instanciação fácil, aceitando o objeto *tokenizer* instanciado como um argumento:
+
+```python
+>>> from transformers import PreTrainedTokenizerFast
+
+>>> fast_tokenizer = PreTrainedTokenizerFast(tokenizer_object=tokenizer)
+```
+Esse objeto pode ser utilizado com todos os métodos compartilhados pelos tokenizers dos 🤗 Transformers! Vá para [a página do tokenizer](main_classes/tokenizer) para mais informações.
+
+## Carregando de um arquivo JSON
+
+Para carregar um tokenizer de um arquivo JSON vamos primeiro começar salvando nosso tokenizer:
+
+```python
+>>> tokenizer.save("tokenizer.json")
+```
+
+A pasta para qual salvamos esse arquivo pode ser passada para o método de inicialização do [`PreTrainedTokenizerFast`] usando o `tokenizer_file` parâmetro:
+
+```python
+>>> from transformers import PreTrainedTokenizerFast
+
+>>> fast_tokenizer = PreTrainedTokenizerFast(tokenizer_file="tokenizer.json")
+```
+
+Esse objeto pode ser utilizado com todos os métodos compartilhados pelos tokenizers dos 🤗 Transformers! Vá para [a página do tokenizer](main_classes/tokenizer) para mais informações.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/index.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/index.md
new file mode 100644
index 0000000000000000000000000000000000000000..18dbcbc06b8048511655b0bbfa5ab75a199696b2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/index.md
@@ -0,0 +1,296 @@
+
+
+# 🤗 Transformers
+
+
+Estado da Arte para Aprendizado de Máquina em PyTorch, TensorFlow e JAX.
+O 🤗 Transformers disponibiliza APIs para facilmente baixar e treinar modelos pré-treinados de última geração.
+O uso de modelos pré-treinados pode diminuir os seus custos de computação, a sua pegada de carbono, além de economizar o
+tempo necessário para se treinar um modelo do zero. Os modelos podem ser usados para diversas tarefas:
+
+* 📝 Textos: classificação, extração de informações, perguntas e respostas, resumir, traduzir e gerar textos em mais de 100 idiomas.
+* 🖼 Imagens: classificação, deteção de objetos, e segmentação.
+* 🗣 Audio: reconhecimento de fala e classificação de áudio.
+* 🐙 Multimodal: perguntas tabeladas e respsostas, reconhecimento ótico de charactéres, extração de informação de
+documentos escaneados, classificação de vídeo, perguntas e respostas visuais.
+
+Nossa biblioteca aceita integração contínua entre três das bibliotecas mais populares de aprendizado profundo:
+Our library supports seamless integration between three of the most popular deep learning libraries:
+[PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/) e [JAX](https://jax.readthedocs.io/en/latest/).
+Treine seu modelo em três linhas de código em um framework, e carregue-o para execução em outro.
+
+Cada arquitetura 🤗 Transformers é definida em um módulo individual do Python, para que seja facilmente customizável para pesquisa e experimentos.
+
+## Se você estiver procurando suporte do time da Hugging Face, acesse
+
+
+
+
+## Conteúdo
+
+A documentação é dividida em cinco partes:
+ - **INÍCIO** contém um tour rápido de instalação e instruções para te dar um empurrão inicial com os 🤗 Transformers.
+ - **TUTORIAIS** são perfeitos para começar a aprender sobre a nossa biblioteca. Essa seção irá te ajudar a desenvolver
+ habilidades básicas necessárias para usar o 🤗 Transformers.
+ - **GUIAS PRÁTICOS** irão te mostrar como alcançar um certo objetivo, como o fine-tuning de um modelo pré-treinado
+ para modelamento de idioma, ou como criar um cabeçalho personalizado para um modelo.
+ - **GUIAS CONCEITUAIS** te darão mais discussões e explicações dos conceitos fundamentais e idéias por trás dos modelos,
+ tarefas e da filosofia de design por trás do 🤗 Transformers.
+ - **API** descreve o funcionamento de cada classe e função, agrupada em:
+
+ - **CLASSES PRINCIPAIS** para as classes que expõe as APIs importantes da biblioteca.
+ - **MODELOS** para as classes e funções relacionadas à cada modelo implementado na biblioteca.
+ - **AUXILIARES INTERNOS** para as classes e funções usadas internamente.
+
+Atualmente a biblioteca contém implementações do PyTorch, TensorFlow e JAX, pesos para modelos pré-treinados e scripts de uso e conversão de utilidades para os seguintes modelos:
+
+### Modelos atuais
+
+
+
+1. **[ALBERT](model_doc/albert)** (from Google Research and the Toyota Technological Institute at Chicago) released with the paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://arxiv.org/abs/1909.11942), by Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
+1. **[BART](model_doc/bart)** (from Facebook) released with the paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://arxiv.org/abs/1910.13461) by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer.
+1. **[BARThez](model_doc/barthez)** (from École polytechnique) released with the paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321) by Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
+1. **[BARTpho](model_doc/bartpho)** (from VinAI Research) released with the paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701) by Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen.
+1. **[BEiT](model_doc/beit)** (from Microsoft) released with the paper [BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254) by Hangbo Bao, Li Dong, Furu Wei.
+1. **[BERT](model_doc/bert)** (from Google) released with the paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805) by Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova.
+1. **[BERTweet](model_doc/bertweet)** (from VinAI Research) released with the paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) by Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen.
+1. **[BERT For Sequence Generation](model_doc/bert-generation)** (from Google) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[BigBird-RoBERTa](model_doc/big_bird)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[Blenderbot](model_doc/blenderbot)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BlenderbotSmall](model_doc/blenderbot-small)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BORT](model_doc/bort)** (from Alexa) released with the paper [Optimal Subarchitecture Extraction For BERT](https://arxiv.org/abs/2010.10499) by Adrian de Wynter and Daniel J. Perry.
+1. **[ByT5](model_doc/byt5)** (from Google Research) released with the paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://arxiv.org/abs/2105.13626) by Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
+1. **[CamemBERT](model_doc/camembert)** (from Inria/Facebook/Sorbonne) released with the paper [CamemBERT: a Tasty French Language Model](https://arxiv.org/abs/1911.03894) by Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot.
+1. **[CANINE](model_doc/canine)** (from Google Research) released with the paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://arxiv.org/abs/2103.06874) by Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
+1. **[ConvNeXT](model_doc/convnext)** (from Facebook AI) released with the paper [A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545) by Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
+1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://arxiv.org/abs/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
+1. **[CLIP](model_doc/clip)** (from OpenAI) released with the paper [Learning Transferable Visual Models From Natural Language Supervision](https://arxiv.org/abs/2103.00020) by Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
+1. **[ConvBERT](model_doc/convbert)** (from YituTech) released with the paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496) by Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
+1. **[CPM](model_doc/cpm)** (from Tsinghua University) released with the paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://arxiv.org/abs/2012.00413) by Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
+1. **[CTRL](model_doc/ctrl)** (from Salesforce) released with the paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://arxiv.org/abs/1909.05858) by Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher.
+1. **[Data2Vec](model_doc/data2vec)** (from Facebook) released with the paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://arxiv.org/abs/2202.03555) by Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
+1. **[DeBERTa](model_doc/deberta)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[DeBERTa-v2](model_doc/deberta-v2)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[Decision Transformer](model_doc/decision_transformer)** (from Berkeley/Facebook/Google) released with the paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://arxiv.org/abs/2106.01345) by Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
+1. **[DiT](model_doc/dit)** (from Microsoft Research) released with the paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://arxiv.org/abs/2203.02378) by Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
+1. **[DeiT](model_doc/deit)** (from Facebook) released with the paper [Training data-efficient image transformers & distillation through attention](https://arxiv.org/abs/2012.12877) by Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
+1. **[DETR](model_doc/detr)** (from Facebook) released with the paper [End-to-End Object Detection with Transformers](https://arxiv.org/abs/2005.12872) by Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
+1. **[DialoGPT](model_doc/dialogpt)** (from Microsoft Research) released with the paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://arxiv.org/abs/1911.00536) by Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
+1. **[DistilBERT](model_doc/distilbert)** (from HuggingFace), released together with the paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://arxiv.org/abs/1910.01108) by Victor Sanh, Lysandre Debut and Thomas Wolf. The same method has been applied to compress GPT2 into [DistilGPT2](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), RoBERTa into [DistilRoBERTa](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), Multilingual BERT into [DistilmBERT](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation) and a German version of DistilBERT.
+1. **[DPR](model_doc/dpr)** (from Facebook) released with the paper [Dense Passage Retrieval for Open-Domain Question Answering](https://arxiv.org/abs/2004.04906) by Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih.
+1. **[DPT](master/model_doc/dpt)** (from Intel Labs) released with the paper [Vision Transformers for Dense Prediction](https://arxiv.org/abs/2103.13413) by René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
+1. **[EfficientNet](model_doc/efficientnet)** (from Google Research) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://arxiv.org/abs/1905.11946) by Mingxing Tan and Quoc V. Le.
+1. **[EncoderDecoder](model_doc/encoder-decoder)** (from Google Research) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[ELECTRA](model_doc/electra)** (from Google Research/Stanford University) released with the paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://arxiv.org/abs/2003.10555) by Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
+1. **[FlauBERT](model_doc/flaubert)** (from CNRS) released with the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://arxiv.org/abs/1912.05372) by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
+1. **[FNet](model_doc/fnet)** (from Google Research) released with the paper [FNet: Mixing Tokens with Fourier Transforms](https://arxiv.org/abs/2105.03824) by James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
+1. **[Funnel Transformer](model_doc/funnel)** (from CMU/Google Brain) released with the paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://arxiv.org/abs/2006.03236) by Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
+1. **[GLPN](model_doc/glpn)** (from KAIST) released with the paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://arxiv.org/abs/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
+1. **[GPT](model_doc/openai-gpt)** (from OpenAI) released with the paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) by Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever.
+1. **[GPT-2](model_doc/gpt2)** (from OpenAI) released with the paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) by Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever.
+1. **[GPT-J](model_doc/gptj)** (from EleutherAI) released in the repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) by Ben Wang and Aran Komatsuzaki.
+1. **[GPT Neo](model_doc/gpt_neo)** (from EleutherAI) released in the repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) by Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy.
+1. **[GPTSAN-japanese](model_doc/gptsan-japanese)** released in the repository [tanreinama/GPTSAN](https://github.com/tanreinama/GPTSAN/blob/main/report/model.md) by Toshiyuki Sakamoto(tanreinama).
+1. **[Hubert](model_doc/hubert)** (from Facebook) released with the paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://arxiv.org/abs/2106.07447) by Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
+1. **[I-BERT](model_doc/ibert)** (from Berkeley) released with the paper [I-BERT: Integer-only BERT Quantization](https://arxiv.org/abs/2101.01321) by Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
+1. **[ImageGPT](model_doc/imagegpt)** (from OpenAI) released with the paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) by Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
+1. **[LayoutLM](model_doc/layoutlm)** (from Microsoft Research Asia) released with the paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://arxiv.org/abs/1912.13318) by Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
+1. **[LayoutLMv2](model_doc/layoutlmv2)** (from Microsoft Research Asia) released with the paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://arxiv.org/abs/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
+1. **[LayoutXLM](model_doc/layoutxlm)** (from Microsoft Research Asia) released with the paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://arxiv.org/abs/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
+1. **[LED](model_doc/led)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[Longformer](model_doc/longformer)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LUKE](model_doc/luke)** (from Studio Ousia) released with the paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://arxiv.org/abs/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
+1. **[mLUKE](model_doc/mluke)** (from Studio Ousia) released with the paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://arxiv.org/abs/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka.
+1. **[LXMERT](model_doc/lxmert)** (from UNC Chapel Hill) released with the paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://arxiv.org/abs/1908.07490) by Hao Tan and Mohit Bansal.
+1. **[M2M100](model_doc/m2m_100)** (from Facebook) released with the paper [Beyond English-Centric Multilingual Machine Translation](https://arxiv.org/abs/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
+1. **[MarianMT](model_doc/marian)** Machine translation models trained using [OPUS](http://opus.nlpl.eu/) data by Jörg Tiedemann. The [Marian Framework](https://marian-nmt.github.io/) is being developed by the Microsoft Translator Team.
+1. **[Mask2Former](model_doc/mask2former)** (from FAIR and UIUC) released with the paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://arxiv.org/abs/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
+1. **[MaskFormer](model_doc/maskformer)** (from Meta and UIUC) released with the paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://arxiv.org/abs/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
+1. **[MBart](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://arxiv.org/abs/2001.08210) by Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
+1. **[MBart-50](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://arxiv.org/abs/2008.00401) by Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
+1. **[Megatron-BERT](model_doc/megatron-bert)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[MPNet](model_doc/mpnet)** (from Microsoft Research) released with the paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://arxiv.org/abs/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
+1. **[MT5](model_doc/mt5)** (from Google AI) released with the paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://arxiv.org/abs/2010.11934) by Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
+1. **[Nyströmformer](model_doc/nystromformer)** (from the University of Wisconsin - Madison) released with the paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://arxiv.org/abs/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
+1. **[OneFormer](model_doc/oneformer)** (from SHI Labs) released with the paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
+1. **[Pegasus](model_doc/pegasus)** (from Google) released with the paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/abs/1912.08777) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu.
+1. **[Perceiver IO](model_doc/perceiver)** (from Deepmind) released with the paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://arxiv.org/abs/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
+1. **[PhoBERT](model_doc/phobert)** (from VinAI Research) released with the paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) by Dat Quoc Nguyen and Anh Tuan Nguyen.
+1. **[PLBart](model_doc/plbart)** (from UCLA NLP) released with the paper [Unified Pre-training for Program Understanding and Generation](https://arxiv.org/abs/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
+1. **[PoolFormer](model_doc/poolformer)** (from Sea AI Labs) released with the paper [MetaFormer is Actually What You Need for Vision](https://arxiv.org/abs/2111.11418) by Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng.
+1. **[ProphetNet](model_doc/prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[QDQBert](model_doc/qdqbert)** (from NVIDIA) released with the paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://arxiv.org/abs/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius.
+1. **[REALM](model_doc/realm.html)** (from Google Research) released with the paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://arxiv.org/abs/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang.
+1. **[Reformer](model_doc/reformer)** (from Google Research) released with the paper [Reformer: The Efficient Transformer](https://arxiv.org/abs/2001.04451) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
+1. **[RemBERT](model_doc/rembert)** (from Google Research) released with the paper [Rethinking embedding coupling in pre-trained language models](https://arxiv.org/abs/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
+1. **[RegNet](model_doc/regnet)** (from META Platforms) released with the paper [Designing Network Design Space](https://arxiv.org/abs/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
+1. **[ResNet](model_doc/resnet)** (from Microsoft Research) released with the paper [Deep Residual Learning for Image Recognition](https://arxiv.org/abs/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
+1. **[RoBERTa](model_doc/roberta)** (from Facebook), released together with the paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://arxiv.org/abs/1907.11692) by Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
+1. **[RoFormer](model_doc/roformer)** (from ZhuiyiTechnology), released together with the paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/abs/2104.09864) by Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu.
+1. **[SegFormer](model_doc/segformer)** (from NVIDIA) released with the paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://arxiv.org/abs/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
+1. **[SEW](model_doc/sew)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SEW-D](model_doc/sew_d)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (from Facebook), released together with the paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
+1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (from Facebook), released together with the paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://arxiv.org/abs/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
+1. **[Splinter](model_doc/splinter)** (from Tel Aviv University), released together with the paper [Few-Shot Question Answering by Pretraining Span Selection](https://arxiv.org/abs/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
+1. **[SqueezeBert](model_doc/squeezebert)** (from Berkeley) released with the paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://arxiv.org/abs/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer.
+1. **[Swin Transformer](model_doc/swin)** (from Microsoft) released with the paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030) by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
+1. **[T5](model_doc/t5)** (from Google AI) released with the paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[T5v1.1](model_doc/t5v1.1)** (from Google AI) released in the repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[TAPAS](model_doc/tapas)** (from Google AI) released with the paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://arxiv.org/abs/2004.02349) by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos.
+1. **[TAPEX](model_doc/tapex)** (from Microsoft Research) released with the paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://arxiv.org/abs/2107.07653) by Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
+1. **[Transformer-XL](model_doc/transfo-xl)** (from Google/CMU) released with the paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://arxiv.org/abs/1901.02860) by Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
+1. **[TrOCR](model_doc/trocr)** (from Microsoft), released together with the paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://arxiv.org/abs/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
+1. **[UniSpeech](model_doc/unispeech)** (from Microsoft Research) released with the paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://arxiv.org/abs/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
+1. **[UniSpeechSat](model_doc/unispeech-sat)** (from Microsoft Research) released with the paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://arxiv.org/abs/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
+1. **[VAN](model_doc/van)** (from Tsinghua University and Nankai University) released with the paper [Visual Attention Network](https://arxiv.org/abs/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
+1. **[ViLT](model_doc/vilt)** (from NAVER AI Lab/Kakao Enterprise/Kakao Brain) released with the paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://arxiv.org/abs/2102.03334) by Wonjae Kim, Bokyung Son, Ildoo Kim.
+1. **[Vision Transformer (ViT)](model_doc/vit)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[ViTMAE](model_doc/vit_mae)** (from Meta AI) released with the paper [Masked Autoencoders Are Scalable Vision Learners](https://arxiv.org/abs/2111.06377) by Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
+1. **[VisualBERT](model_doc/visual_bert)** (from UCLA NLP) released with the paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://arxiv.org/pdf/1908.03557) by Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
+1. **[WavLM](model_doc/wavlm)** (from Microsoft Research) released with the paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://arxiv.org/abs/2110.13900) by Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
+1. **[Wav2Vec2](model_doc/wav2vec2)** (from Facebook AI) released with the paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://arxiv.org/abs/2006.11477) by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
+1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (from Facebook AI) released with the paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://arxiv.org/abs/2109.11680) by Qiantong Xu, Alexei Baevski, Michael Auli.
+1. **[XGLM](model_doc/xglm)** (From Facebook AI) released with the paper [Few-shot Learning with Multilingual Language Models](https://arxiv.org/abs/2112.10668) by Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
+1. **[XLM](model_doc/xlm)** (from Facebook) released together with the paper [Cross-lingual Language Model Pretraining](https://arxiv.org/abs/1901.07291) by Guillaume Lample and Alexis Conneau.
+1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (from Facebook AI), released together with the paper [Unsupervised Cross-lingual Representation Learning at Scale](https://arxiv.org/abs/1911.02116) by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
+1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (from Facebook AI), released together with the paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://arxiv.org/abs/2105.00572) by Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
+1. **[XLNet](model_doc/xlnet)** (from Google/CMU) released with the paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://arxiv.org/abs/1906.08237) by Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
+1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (from Facebook AI) released with the paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://arxiv.org/abs/2006.13979) by Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
+1. **[XLS-R](model_doc/xls_r)** (from Facebook AI) released with the paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://arxiv.org/abs/2111.09296) by Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
+1. **[YOSO](model_doc/yoso)** (from the University of Wisconsin - Madison) released with the paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://arxiv.org/abs/2111.09714) by Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
+
+
+### Frameworks aceitos
+
+A tabela abaixo representa a lista de suporte na biblioteca para cada um dos seguintes modelos, caso tenham um tokenizer
+do Python (chamado de "slow"), ou um tokenizer construído em cima da biblioteca 🤗 Tokenizers (chamado de "fast"). Além
+disso, são diferenciados pelo suporte em diferentes frameworks: JAX (por meio do Flax); PyTorch; e/ou Tensorflow.
+
+
+
+| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
+|:---------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
+| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
+| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
+| BigBirdPegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
+| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Canine | ✅ | ❌ | ✅ | ❌ | ❌ |
+| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
+| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ConvNext | ❌ | ❌ | ✅ | ✅ | ❌ |
+| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecVision | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeiT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
+| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
+| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
+| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
+| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
+| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MegatronBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| mT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Nystromformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Realm | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ResNet | ❌ | ❌ | ✅ | ❌ | ✅ |
+| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
+| SegFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
+| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Swin | ❌ | ❌ | ✅ | ❌ | ❌ |
+| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TAPEX | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| VisualBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
+| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XGLM | ✅ | ✅ | ✅ | ❌ | ✅ |
+| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XLMProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/installation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/installation.md
new file mode 100644
index 0000000000000000000000000000000000000000..f548736589ac0d81bc7ebe2d73d60652ce03040b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/installation.md
@@ -0,0 +1,262 @@
+
+
+# Guia de Instalação
+
+Neste guia poderá encontrar informações para a instalação do 🤗 Transformers para qualquer biblioteca de
+Machine Learning com a qual esteja a trabalhar. Além disso, poderá encontrar informações sobre como gerar cachês e
+configurar o 🤗 Transformers para execução em modo offline (opcional).
+
+🤗 Transformers foi testado com Python 3.6+, PyTorch 1.1.0+, TensorFlow 2.0+, e Flax. Para instalar a biblioteca de
+deep learning com que deseja trabalhar, siga as instruções correspondentes listadas a seguir:
+
+* [PyTorch](https://pytorch.org/get-started/locally/)
+* [TensorFlow 2.0](https://www.tensorflow.org/install/pip)
+* [Flax](https://flax.readthedocs.io/en/latest/)
+
+## Instalação pelo Pip
+
+É sugerido instalar o 🤗 Transformers num [ambiente virtual](https://docs.python.org/3/library/venv.html). Se precisar
+de mais informações sobre ambientes virtuais em Python, consulte este [guia](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/).
+Um ambiente virtual facilitará a manipulação e organização de projetos e evita problemas de compatibilidade entre dependências.
+
+Comece criando um ambiente virtual no diretório do seu projeto:
+
+```bash
+python -m venv .env
+```
+
+E para ativar o ambiente virtual:
+
+```bash
+source .env/bin/activate
+```
+
+Agora É possível instalar o 🤗 Transformers com o comando a seguir:
+
+```bash
+pip install transformers
+```
+
+Somente para a CPU, é possível instalar o 🤗 Transformers e a biblioteca de deep learning respectiva apenas numa linha.
+
+Por exemplo, para instalar o 🤗 Transformers e o PyTorch, digite:
+
+```bash
+pip install transformers[torch]
+```
+
+🤗 Transformers e TensorFlow 2.0:
+
+```bash
+pip install transformers[tf-cpu]
+```
+
+🤗 Transformers e Flax:
+
+```bash
+pip install transformers[flax]
+```
+
+Por último, verifique se o 🤗 Transformers foi instalado com sucesso usando o seguinte comando para baixar um modelo pré-treinado:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('we love you'))"
+```
+
+Em seguida, imprima um rótulo e sua pontuação:
+
+```bash
+[{'label': 'POSITIVE', 'score': 0.9998704791069031}]
+```
+
+## Instalação usando a fonte
+
+Para instalar o 🤗 Transformers a partir da fonte use o seguinte comando:
+
+```bash
+pip install git+https://github.com/huggingface/transformers
+```
+
+O comando acima instalará a versão `master` mais atual em vez da última versão estável. A versão `master` é útil para
+utilizar os últimos updates contidos em 🤗 Transformers. Por exemplo, um erro recente pode ter sido corrigido somente
+após a última versão estável, antes que houvesse um novo lançamento. No entanto, há a possibilidade que a versão `master` não esteja estável.
+A equipa trata de mantér a versão `master` operacional e a maioria dos erros são resolvidos em poucas horas ou dias.
+Se encontrar quaisquer problemas, por favor abra um [Issue](https://github.com/huggingface/transformers/issues) para que o
+mesmo possa ser corrigido o mais rápido possível.
+
+Verifique que o 🤗 Transformers está instalado corretamente usando o seguinte comando:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('I love you'))"
+```
+
+## Instalação editável
+
+Uma instalação editável será necessária caso desejas um dos seguintes:
+* Usar a versão `master` do código fonte.
+* Contribuir ao 🤗 Transformers e precisa testar mudanças ao código.
+
+Para tal, clone o repositório e instale o 🤗 Transformers com os seguintes comandos:
+
+```bash
+git clone https://github.com/huggingface/transformers.git
+cd transformers
+pip install -e .
+```
+
+Estes comandos vão ligar o diretório para o qual foi clonado o repositório ao caminho de bibliotecas do Python.
+O Python agora buscará dentro dos arquivos que foram clonados além dos caminhos normais da biblioteca.
+Por exemplo, se os pacotes do Python se encontram instalados no caminho `~/anaconda3/envs/main/lib/python3.7/site-packages/`,
+o Python também buscará módulos no diretório onde clonamos o repositório `~/transformers/`.
+
+
+
+É necessário manter o diretório `transformers` se desejas continuar usando a biblioteca.
+
+
+
+Assim, É possível atualizar sua cópia local para com a última versão do 🤗 Transformers com o seguinte comando:
+
+```bash
+cd ~/transformers/
+git pull
+```
+
+O ambiente de Python que foi criado para a instalação do 🤗 Transformers encontrará a versão `master` em execuções seguintes.
+
+## Instalação usando o Conda
+
+É possível instalar o 🤗 Transformers a partir do canal conda `conda-forge` com o seguinte comando:
+
+```bash
+conda install conda-forge::transformers
+```
+
+## Configuração do Cachê
+
+Os modelos pré-treinados são baixados e armazenados no cachê local, encontrado em `~/.cache/huggingface/transformers/`.
+Este é o diretório padrão determinado pela variável `TRANSFORMERS_CACHE` dentro do shell.
+No Windows, este diretório pré-definido é dado por `C:\Users\username\.cache\huggingface\transformers`.
+É possível mudar as variáveis dentro do shell em ordem de prioridade para especificar um diretório de cachê diferente:
+
+1. Variável de ambiente do shell (por padrão): `TRANSFORMERS_CACHE`.
+2. Variável de ambiente do shell:`HF_HOME` + `transformers/`.
+3. Variável de ambiente do shell: `XDG_CACHE_HOME` + `/huggingface/transformers`.
+
+
+
+ O 🤗 Transformers usará as variáveis de ambiente do shell `PYTORCH_TRANSFORMERS_CACHE` ou `PYTORCH_PRETRAINED_BERT_CACHE`
+ se estiver vindo de uma versão anterior da biblioteca que tenha configurado essas variáveis de ambiente, a menos que
+ você especifique a variável de ambiente do shell `TRANSFORMERS_CACHE`.
+
+
+
+
+## Modo Offline
+
+O 🤗 Transformers também pode ser executado num ambiente de firewall ou fora da rede (offline) usando arquivos locais.
+Para tal, configure a variável de ambiente de modo que `HF_HUB_OFFLINE=1`.
+
+
+
+Você pode adicionar o [🤗 Datasets](https://huggingface.co/docs/datasets/) ao pipeline de treinamento offline declarando
+ a variável de ambiente `HF_DATASETS_OFFLINE=1`.
+
+
+
+Segue um exemplo de execução do programa numa rede padrão com firewall para instâncias externas, usando o seguinte comando:
+
+```bash
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+Execute esse mesmo programa numa instância offline com o seguinte comando:
+
+```bash
+HF_DATASETS_OFFLINE=1 HF_HUB_OFFLINE=1 \
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+O script agora deve ser executado sem travar ou expirar, pois procurará apenas por arquivos locais.
+
+### Obtendo modelos e tokenizers para uso offline
+
+Outra opção para usar o 🤗 Transformers offline é baixar os arquivos antes e depois apontar para o caminho local onde estão localizados. Existem três maneiras de fazer isso:
+
+* Baixe um arquivo por meio da interface de usuário do [Model Hub](https://huggingface.co/models) clicando no ícone ↓.
+
+ 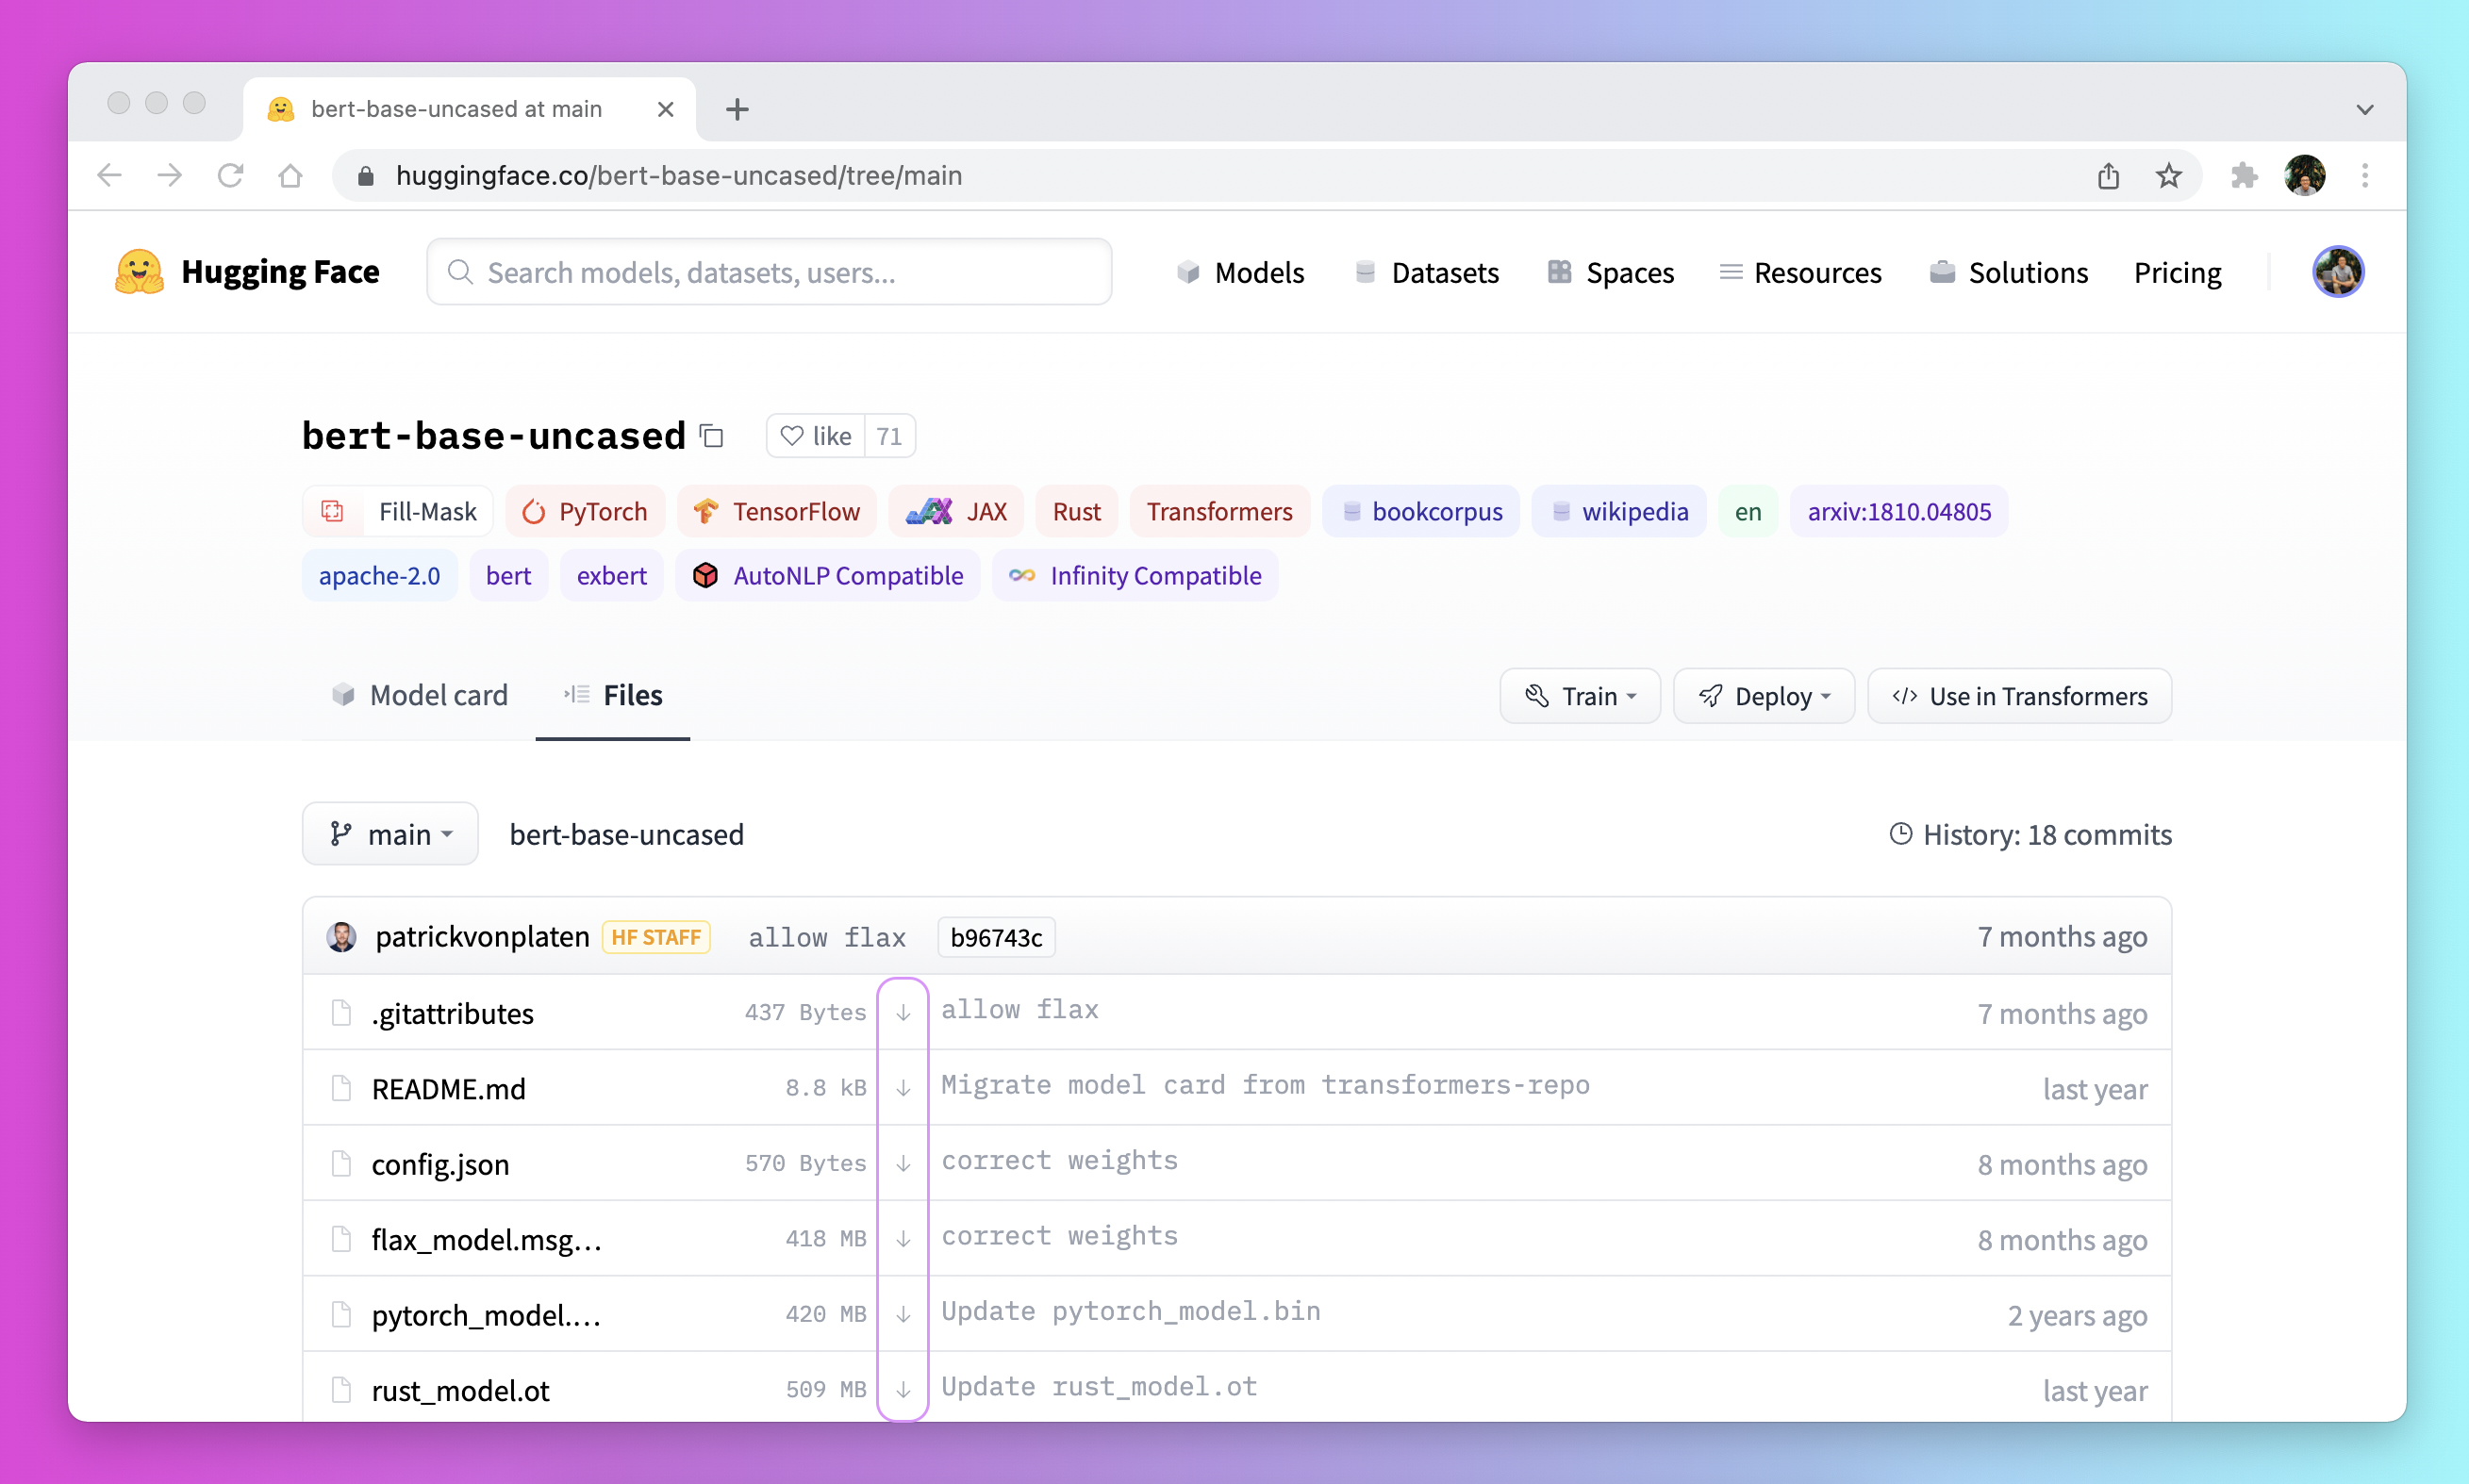
+
+
+* Use o pipeline do [`PreTrainedModel.from_pretrained`] e [`PreTrainedModel.save_pretrained`]:
+ 1. Baixa os arquivos previamente com [`PreTrainedModel.from_pretrained`]:
+
+ ```py
+ >>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("bigscience/T0_3B")
+ >>> model = AutoModelForSeq2SeqLM.from_pretrained("bigscience/T0_3B")
+ ```
+
+
+ 2. Salve os arquivos em um diretório específico com [`PreTrainedModel.save_pretrained`]:
+
+ ```py
+ >>> tokenizer.save_pretrained("./your/path/bigscience_t0")
+ >>> model.save_pretrained("./your/path/bigscience_t0")
+ ```
+
+ 3. Quando estiver offline, acesse os arquivos com [`PreTrainedModel.from_pretrained`] do diretório especificado:
+
+ ```py
+ >>> tokenizer = AutoTokenizer.from_pretrained("./your/path/bigscience_t0")
+ >>> model = AutoModel.from_pretrained("./your/path/bigscience_t0")
+ ```
+
+* Baixando arquivos programaticamente com a biblioteca [huggingface_hub](https://github.com/huggingface/huggingface_hub/tree/main/src/huggingface_hub):
+
+ 1. Instale a biblioteca [huggingface_hub](https://github.com/huggingface/huggingface_hub/tree/main/src/huggingface_hub) em seu ambiente virtual:
+
+ ```bash
+ python -m pip install huggingface_hub
+ ```
+
+ 2. Utiliza a função [`hf_hub_download`](https://huggingface.co/docs/hub/adding-a-library#download-files-from-the-hub) para baixar um arquivo para um caminho específico. Por exemplo, o comando a seguir baixará o arquivo `config.json` para o modelo [T0](https://huggingface.co/bigscience/T0_3B) no caminho desejado:
+
+ ```py
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> hf_hub_download(repo_id="bigscience/T0_3B", filename="config.json", cache_dir="./your/path/bigscience_t0")
+ ```
+
+Depois que o arquivo for baixado e armazenado no cachê local, especifique seu caminho local para carregá-lo e usá-lo:
+
+```py
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("./your/path/bigscience_t0/config.json")
+```
+
+
+
+Para obter mais detalhes sobre como baixar arquivos armazenados no Hub, consulte a seção [How to download files from the Hub](https://huggingface.co/docs/hub/how-to-downstream).
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/multilingual.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/multilingual.md
new file mode 100644
index 0000000000000000000000000000000000000000..5515c6a922a7019b60f7b8e9baf0eb1ab0f84c43
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/multilingual.md
@@ -0,0 +1,195 @@
+
+
+# Modelos multilinguísticos para inferência
+
+[[open-in-colab]]
+
+Existem vários modelos multilinguísticos no 🤗 Transformers e seus usos para inferência diferem dos modelos monolíngues.
+No entanto, nem *todos* os usos dos modelos multilíngues são tão diferentes.
+Alguns modelos, como o [google-bert/bert-base-multilingual-uncased](https://huggingface.co/google-bert/bert-base-multilingual-uncased),
+podem ser usados como se fossem monolíngues. Este guia irá te ajudar a usar modelos multilíngues cujo uso difere
+para o propósito de inferência.
+
+## XLM
+
+O XLM tem dez checkpoints diferentes dos quais apenas um é monolíngue.
+Os nove checkpoints restantes do modelo são subdivididos em duas categorias:
+checkpoints que usam de language embeddings e os que não.
+
+### XLM com language embeddings
+
+Os seguintes modelos de XLM usam language embeddings para especificar a linguagem utilizada para a inferência.
+
+- `FacebookAI/xlm-mlm-ende-1024` (Masked language modeling, English-German)
+- `FacebookAI/xlm-mlm-enfr-1024` (Masked language modeling, English-French)
+- `FacebookAI/xlm-mlm-enro-1024` (Masked language modeling, English-Romanian)
+- `FacebookAI/xlm-mlm-xnli15-1024` (Masked language modeling, XNLI languages)
+- `FacebookAI/xlm-mlm-tlm-xnli15-1024` (Masked language modeling + translation, XNLI languages)
+- `FacebookAI/xlm-clm-enfr-1024` (Causal language modeling, English-French)
+- `FacebookAI/xlm-clm-ende-1024` (Causal language modeling, English-German)
+
+Os language embeddings são representados por um tensor de mesma dimensão que os `input_ids` passados ao modelo.
+Os valores destes tensores dependem do idioma utilizado e se identificam pelos atributos `lang2id` e `id2lang` do tokenizador.
+
+Neste exemplo, carregamos o checkpoint `FacebookAI/xlm-clm-enfr-1024`(Causal language modeling, English-French):
+
+```py
+>>> import torch
+>>> from transformers import XLMTokenizer, XLMWithLMHeadModel
+
+>>> tokenizer = XLMTokenizer.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
+>>> model = XLMWithLMHeadModel.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
+```
+
+O atributo `lang2id` do tokenizador mostra os idiomas deste modelo e seus ids:
+
+```py
+>>> print(tokenizer.lang2id)
+{'en': 0, 'fr': 1}
+```
+
+Em seguida, cria-se um input de exemplo:
+
+```py
+>>> input_ids = torch.tensor([tokenizer.encode("Wikipedia was used to")]) # batch size of 1
+```
+
+Estabelece-se o id do idioma, por exemplo `"en"`, e utiliza-se o mesmo para definir a language embedding.
+A language embedding é um tensor preenchido com `0`, que é o id de idioma para o inglês.
+Este tensor deve ser do mesmo tamanho que os `input_ids`.
+
+```py
+>>> language_id = tokenizer.lang2id["en"] # 0
+>>> langs = torch.tensor([language_id] * input_ids.shape[1]) # torch.tensor([0, 0, 0, ..., 0])
+
+>>> # We reshape it to be of size (batch_size, sequence_length)
+>>> langs = langs.view(1, -1) # is now of shape [1, sequence_length] (we have a batch size of 1)
+```
+
+Agora você pode passar os `input_ids` e a language embedding ao modelo:
+
+```py
+>>> outputs = model(input_ids, langs=langs)
+```
+
+O script [run_generation.py](https://github.com/huggingface/transformers/tree/master/examples/pytorch/text-generation/run_generation.py) pode gerar um texto com language embeddings utilizando os checkpoints `xlm-clm`.
+
+### XLM sem language embeddings
+
+Os seguintes modelos XLM não requerem o uso de language embeddings durante a inferência:
+
+- `FacebookAI/xlm-mlm-17-1280` (Modelagem de linguagem com máscara, 17 idiomas)
+- `FacebookAI/xlm-mlm-100-1280` (Modelagem de linguagem com máscara, 100 idiomas)
+
+Estes modelos são utilizados para representações genéricas de frase diferentemente dos checkpoints XLM anteriores.
+
+## BERT
+
+Os seguintes modelos do BERT podem ser utilizados para tarefas multilinguísticas:
+
+- `google-bert/bert-base-multilingual-uncased` (Modelagem de linguagem com máscara + Previsão de frases, 102 idiomas)
+- `google-bert/bert-base-multilingual-cased` (Modelagem de linguagem com máscara + Previsão de frases, 104 idiomas)
+
+Estes modelos não requerem language embeddings durante a inferência. Devem identificar a linguagem a partir
+do contexto e realizar a inferência em sequência.
+
+## XLM-RoBERTa
+
+Os seguintes modelos do XLM-RoBERTa podem ser utilizados para tarefas multilinguísticas:
+
+- `FacebookAI/xlm-roberta-base` (Modelagem de linguagem com máscara, 100 idiomas)
+- `FacebookAI/xlm-roberta-large` Modelagem de linguagem com máscara, 100 idiomas)
+
+O XLM-RoBERTa foi treinado com 2,5 TB de dados do CommonCrawl recém-criados e testados em 100 idiomas.
+Proporciona fortes vantagens sobre os modelos multilinguísticos publicados anteriormente como o mBERT e o XLM em tarefas
+subsequentes como a classificação, a rotulagem de sequências e à respostas a perguntas.
+
+## M2M100
+
+Os seguintes modelos de M2M100 podem ser utilizados para traduções multilinguísticas:
+
+- `facebook/m2m100_418M` (Tradução)
+- `facebook/m2m100_1.2B` (Tradução)
+
+Neste exemplo, o checkpoint `facebook/m2m100_418M` é carregado para traduzir do mandarim ao inglês. É possível
+estabelecer o idioma de origem no tokenizador:
+
+```py
+>>> from transformers import M2M100ForConditionalGeneration, M2M100Tokenizer
+
+>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
+>>> chinese_text = "不要插手巫師的事務, 因為他們是微妙的, 很快就會發怒."
+
+>>> tokenizer = M2M100Tokenizer.from_pretrained("facebook/m2m100_418M", src_lang="zh")
+>>> model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M")
+```
+
+Tokenização do texto:
+
+```py
+>>> encoded_zh = tokenizer(chinese_text, return_tensors="pt")
+```
+
+O M2M100 força o id do idioma de destino como o primeiro token gerado para traduzir ao idioma de destino.
+É definido o `forced_bos_token_id` como `en` no método `generate` para traduzir ao inglês.
+
+```py
+>>> generated_tokens = model.generate(**encoded_zh, forced_bos_token_id=tokenizer.get_lang_id("en"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+'Do not interfere with the matters of the witches, because they are delicate and will soon be angry.'
+```
+
+## MBart
+
+Os seguintes modelos do MBart podem ser utilizados para tradução multilinguística:
+
+- `facebook/mbart-large-50-one-to-many-mmt` (Tradução automática multilinguística de um a vários, 50 idiomas)
+- `facebook/mbart-large-50-many-to-many-mmt` (Tradução automática multilinguística de vários a vários, 50 idiomas)
+- `facebook/mbart-large-50-many-to-one-mmt` (Tradução automática multilinguística vários a um, 50 idiomas)
+- `facebook/mbart-large-50` (Tradução multilinguística, 50 idiomas)
+- `facebook/mbart-large-cc25`
+
+Neste exemplo, carrega-se o checkpoint `facebook/mbart-large-50-many-to-many-mmt` para traduzir do finlandês ao inglês.
+Pode-se definir o idioma de origem no tokenizador:
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
+>>> fi_text = "Älä sekaannu velhojen asioihin, sillä ne ovat hienovaraisia ja nopeasti vihaisia."
+
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/mbart-large-50-many-to-many-mmt", src_lang="fi_FI")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/mbart-large-50-many-to-many-mmt")
+```
+
+Tokenizando o texto:
+
+```py
+>>> encoded_en = tokenizer(en_text, return_tensors="pt")
+```
+
+O MBart força o id do idioma de destino como o primeiro token gerado para traduzir ao idioma de destino.
+É definido o `forced_bos_token_id` como `en` no método `generate` para traduzir ao inglês.
+
+```py
+>>> generated_tokens = model.generate(**encoded_en, forced_bos_token_id=tokenizer.lang_code_to_id("en_XX"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+"Don't interfere with the wizard's affairs, because they are subtle, will soon get angry."
+```
+
+Se estiver usando o checkpoint `facebook/mbart-large-50-many-to-one-mmt` não será necessário forçar o id do idioma de destino
+como sendo o primeiro token generado, caso contrário a usagem é a mesma.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/pipeline_tutorial.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/pipeline_tutorial.md
new file mode 100644
index 0000000000000000000000000000000000000000..9c0cb3567e72e38c373d60e7fd9813000333eef1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/pipeline_tutorial.md
@@ -0,0 +1,157 @@
+
+
+# Pipelines para inferência
+
+Um [pipeline] simplifica o uso dos modelos no [Model Hub](https://huggingface.co/models) para a inferência de uma diversidade de tarefas,
+como a geração de texto, a segmentação de imagens e a classificação de áudio.
+Inclusive, se não tem experiência com alguma modalidade específica ou não compreende o código que forma os modelos,
+pode usar eles mesmo assim com o [pipeline]! Este tutorial te ensinará a:
+
+* Utilizar um [`pipeline`] para inferência.
+* Utilizar um tokenizador ou model específico.
+* Utilizar um [`pipeline`] para tarefas de áudio e visão computacional.
+
+
+
+ Acesse a documentação do [`pipeline`] para obter uma lista completa de tarefas possíveis.
+
+
+
+## Uso do pipeline
+
+Mesmo que cada tarefa tenha um [`pipeline`] associado, é mais simples usar a abstração geral do [`pipeline`] que
+contém todos os pipelines das tarefas mais específicas.
+O [`pipeline`] carrega automaticamenta um modelo predeterminado e um tokenizador com capacidade de inferência para sua
+tarefa.
+
+1. Comece carregando um [`pipeline`] e especifique uma tarefa de inferência:
+
+```py
+>>> from transformers import pipeline
+
+>>> generator = pipeline(task="text-generation")
+```
+
+2. Passe seu dado de entrada, no caso um texto, ao [`pipeline`]:
+
+```py
+>>> generator("Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone")
+[{'generated_text': 'Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone, Seven for the Iron-priests at the door to the east, and thirteen for the Lord Kings at the end of the mountain'}]
+```
+
+Se tiver mais de uma entrada, passe-a como uma lista:
+
+```py
+>>> generator(
+... [
+... "Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone",
+... "Nine for Mortal Men, doomed to die, One for the Dark Lord on his dark throne",
+... ]
+... )
+```
+
+Qualquer parâmetro adicional para a sua tarefa também pode ser incluído no [`pipeline`]. A tarefa `text-generation` tem um método
+[`~generation.GenerationMixin.generate`] com vários parâmetros para controlar a saída.
+Por exemplo, se quiser gerar mais de uma saída, defina-a no parâmetro `num_return_sequences`:
+
+```py
+>>> generator(
+... "Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone",
+... num_return_sequences=2,
+... )
+```
+
+### Selecionando um modelo e um tokenizador
+
+O [`pipeline`] aceita qualquer modelo do [Model Hub](https://huggingface.co/models). Há rótulos adicionais no Model Hub
+que te permitem filtrar pelo modelo que gostaria de usar para sua tarefa. Uma vez que tiver escolhido o modelo apropriado,
+carregue-o com as classes `AutoModelFor` e [`AutoTokenizer`] correspondentes. Por exemplo, carregue a classe [`AutoModelForCausalLM`]
+para uma tarefa de modelagem de linguagem causal:
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForCausalLM
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilgpt2")
+>>> model = AutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+```
+
+Crie uma [`pipeline`] para a sua tarefa e especifíque o modelo e o tokenizador que foram carregados:
+
+```py
+>>> from transformers import pipeline
+
+>>> generator = pipeline(task="text-generation", model=model, tokenizer=tokenizer)
+```
+
+Passe seu texto de entrada ao [`pipeline`] para gerar algum texto:
+
+```py
+>>> generator("Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone")
+[{'generated_text': 'Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone, Seven for the Dragon-lords (for them to rule in a world ruled by their rulers, and all who live within the realm'}]
+```
+
+## Pipeline de audio
+
+A flexibilidade do [`pipeline`] significa que também pode-se extender às tarefas de áudio.
+La flexibilidad de [`pipeline`] significa que también se puede extender a tareas de audio.
+
+Por exemplo, classifiquemos a emoção de um breve fragmento do famoso discurso de John F. Kennedy /home/rzimmerdev/dev/transformers/docs/source/pt/pipeline_tutorial.md
+Encontre um modelo de [audio classification](https://huggingface.co/models?pipeline_tag=audio-classification) para
+reconhecimento de emoções no Model Hub e carregue-o usando o [`pipeline`]:
+
+```py
+>>> from transformers import pipeline
+
+>>> audio_classifier = pipeline(
+... task="audio-classification", model="ehcalabres/wav2vec2-lg-xlsr-en-speech-emotion-recognition"
+... )
+```
+
+Passe o arquivo de áudio ao [`pipeline`]:
+
+```py
+>>> audio_classifier("jfk_moon_speech.wav")
+[{'label': 'calm', 'score': 0.13856211304664612},
+ {'label': 'disgust', 'score': 0.13148026168346405},
+ {'label': 'happy', 'score': 0.12635163962841034},
+ {'label': 'angry', 'score': 0.12439591437578201},
+ {'label': 'fearful', 'score': 0.12404385954141617}]
+```
+
+## Pipeline de visão computacional
+
+Finalmente, utilizar um [`pipeline`] para tarefas de visão é praticamente a mesma coisa.
+Especifique a sua tarefa de visão e passe a sua imagem ao classificador.
+A imagem pode ser um link ou uma rota local à imagem. Por exemplo, que espécie de gato está presente na imagem?
+
+
+
+```py
+>>> from transformers import pipeline
+
+>>> vision_classifier = pipeline(task="image-classification")
+>>> vision_classifier(
+... images="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+[{'label': 'lynx, catamount', 'score': 0.4403027892112732},
+ {'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor',
+ 'score': 0.03433405980467796},
+ {'label': 'snow leopard, ounce, Panthera uncia',
+ 'score': 0.032148055732250214},
+ {'label': 'Egyptian cat', 'score': 0.02353910356760025},
+ {'label': 'tiger cat', 'score': 0.023034192621707916}]
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/quicktour.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/quicktour.md
new file mode 100644
index 0000000000000000000000000000000000000000..cc583697b9a65880c13b4aa9604eb3a3c4e3287c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/quicktour.md
@@ -0,0 +1,399 @@
+
+
+# Tour rápido
+
+[[open-in-colab]]
+
+Comece a trabalhar com 🤗 Transformers! Comece usando [`pipeline`] para rápida inferência e facilmente carregue um modelo pré-treinado e um tokenizer com [AutoClass](./model_doc/auto) para resolver tarefas de texto, visão ou áudio.
+
+
+
+Todos os exemplos de código apresentados na documentação têm um botão no canto superior direito para escolher se você deseja ocultar ou mostrar o código no Pytorch ou no TensorFlow. Caso contrário, é esperado que funcione para ambos back-ends sem nenhuma alteração.
+
+
+
+## Pipeline
+
+[`pipeline`] é a maneira mais fácil de usar um modelo pré-treinado para uma dada tarefa.
+
+
+
+Para mais detalhes sobre a [`pipeline`] e tarefas associadas, siga a documentação [aqui](./main_classes/pipelines).
+
+
+
+### Uso da pipeline
+
+No exemplo a seguir, você usará [`pipeline`] para análise sentimental.
+
+Instale as seguintes dependências se você ainda não o fez:
+
+
+
+
+```bash
+pip install torch
+```
+
+
+```bash
+pip install tensorflow
+```
+
+
+
+Importe [`pipeline`] e especifique a tarefa que deseja completar:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("sentiment-analysis")
+```
+
+A pipeline baixa and armazena um [modelo pré-treinado](https://huggingface.co/distilbert/distilbert-base-uncased-finetuned-sst-2-english) padrão e tokenizer para análise sentimental. Agora você pode usar `classifier` no texto alvo:
+
+```py
+>>> classifier("We are very happy to show you the 🤗 Transformers library.")
+[{'label': 'POSITIVE', 'score': 0.9998}]
+```
+
+Para mais de uma sentença, passe uma lista para a [`pipeline`], a qual retornará uma lista de dicionários:
+
+```py
+>>> results = classifier(["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."])
+>>> for result in results:
+... print(f"label: {result['label']}, with score: {round(result['score'], 4)}")
+label: POSITIVE, with score: 0.9998
+label: NEGATIVE, with score: 0.5309
+```
+
+A [`pipeline`] também pode iterar sobre um Dataset inteiro. Comece instalando a biblioteca de [🤗 Datasets](https://huggingface.co/docs/datasets/):
+
+```bash
+pip install datasets
+```
+
+Crie uma [`pipeline`] com a tarefa que deseja resolver e o modelo que deseja usar.
+
+```py
+>>> import torch
+>>> from transformers import pipeline
+
+>>> speech_recognizer = pipeline("automatic-speech-recognition", model="facebook/wav2vec2-base-960h")
+```
+
+A seguir, carregue uma base de dados (confira a 🤗 [Iniciação em Datasets](https://huggingface.co/docs/datasets/quickstart) para mais detalhes) que você gostaria de iterar sobre. Por exemplo, vamos carregar o dataset [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14):
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train") # doctest: +IGNORE_RESULT
+```
+
+Precisamos garantir que a taxa de amostragem do conjunto de dados corresponda à taxa de amostragem em que o facebook/wav2vec2-base-960h foi treinado.
+
+```py
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=speech_recognizer.feature_extractor.sampling_rate))
+```
+
+Os arquivos de áudio são carregados e re-amostrados automaticamente ao chamar a coluna `"audio"`.
+Vamos extrair as arrays de formas de onda originais das primeiras 4 amostras e passá-las como uma lista para o pipeline:
+
+```py
+>>> result = speech_recognizer(dataset[:4]["audio"])
+>>> print([d["text"] for d in result])
+['I WOULD LIKE TO SET UP A JOINT ACCOUNT WITH MY PARTNER HOW DO I PROCEED WITH DOING THAT', "FONDERING HOW I'D SET UP A JOIN TO HET WITH MY WIFE AND WHERE THE AP MIGHT BE", "I I'D LIKE TOY SET UP A JOINT ACCOUNT WITH MY PARTNER I'M NOT SEEING THE OPTION TO DO IT ON THE APSO I CALLED IN TO GET SOME HELP CAN I JUST DO IT OVER THE PHONE WITH YOU AND GIVE YOU THE INFORMATION OR SHOULD I DO IT IN THE AP AND I'M MISSING SOMETHING UQUETTE HAD PREFERRED TO JUST DO IT OVER THE PHONE OF POSSIBLE THINGS", 'HOW DO I TURN A JOIN A COUNT']
+```
+
+Para um conjunto de dados maior onde as entradas são maiores (como em fala ou visão), será necessário passar um gerador em vez de uma lista que carregue todas as entradas na memória. Consulte a [documentação do pipeline](./main_classes/pipelines) para mais informações.
+
+### Use outro modelo e tokenizer na pipeline
+
+A [`pipeline`] pode acomodar qualquer modelo do [Model Hub](https://huggingface.co/models), facilitando sua adaptação para outros casos de uso. Por exemplo, se você quiser um modelo capaz de lidar com texto em francês, use as tags no Model Hub para filtrar um modelo apropriado. O principal resultado filtrado retorna um [modelo BERT](https://huggingface.co/nlptown/bert-base-multilingual-uncased-sentiment) bilíngue ajustado para análise de sentimentos. Ótimo, vamos usar este modelo!
+
+```py
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+```
+
+
+
+Use o [`AutoModelForSequenceClassification`] e [`AutoTokenizer`] para carregar o modelo pré-treinado e seu tokenizer associado (mais em `AutoClass` abaixo):
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+
+Use o [`TFAutoModelForSequenceClassification`] and [`AutoTokenizer`] para carregar o modelo pré-treinado e o tokenizer associado (mais em `TFAutoClass` abaixo):
+
+```py
+>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+
+Então você pode especificar o modelo e o tokenizador na [`pipeline`] e aplicar o `classifier` no seu texto alvo:
+
+```py
+>>> classifier = pipeline("sentiment-analysis", model=model, tokenizer=tokenizer)
+>>> classifier("Nous sommes très heureux de vous présenter la bibliothèque 🤗 Transformers.")
+[{'label': '5 stars', 'score': 0.7273}]
+```
+
+Se você não conseguir achar um modelo para o seu caso de uso, precisará usar fine-tune em um modelo pré-treinado nos seus dados. Veja nosso [tutorial de fine-tuning](./training) para descobrir como. Finalmente, depois que você tiver usado esse processo em seu modelo, considere compartilhá-lo conosco (veja o tutorial [aqui](./model_sharing)) na plataforma Model Hub afim de democratizar NLP! 🤗
+
+## AutoClass
+
+
+
+
+```py
+>>> pt_batch = tokenizer(
+... ["We are very happy to show you the 🤗 transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="pt",
+... )
+```
+
+
+
+```py
+>>> tf_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="tf",
+... )
+```
+
+
+
+Leia o tutorial de [pré-processamento](./pré-processamento) para obter mais detalhes sobre tokenização.
+
+### AutoModel
+
+
+
+🤗 Transformers fornecem uma maneira simples e unificada de carregar instâncias pré-treinadas. Isso significa que você pode carregar um [`AutoModel`] como carregaria um [`AutoTokenizer`]. A única diferença é selecionar o [`AutoModel`] correto para a tarefa. Como você está fazendo classificação de texto ou sequência, carregue [`AutoModelForSequenceClassification`]:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+Veja o [sumário de tarefas](./task_summary) para qual classe de [`AutoModel`] usar para cada tarefa.
+
+
+
+Agora você pode passar seu grupo de entradas pré-processadas diretamente para o modelo. Você apenas tem que descompactar o dicionário usando `**`:
+
+```py
+>>> pt_outputs = pt_model(**pt_batch)
+```
+
+O modelo gera as ativações finais no atributo `logits`. Aplique a função softmax aos `logits` para recuperar as probabilidades:
+
+```py
+>>> from torch import nn
+
+>>> pt_predictions = nn.functional.softmax(pt_outputs.logits, dim=-1)
+>>> print(pt_predictions)
+tensor([[0.0021, 0.0018, 0.0115, 0.2121, 0.7725],
+ [0.2084, 0.1826, 0.1969, 0.1755, 0.2365]], grad_fn=)
+```
+
+
+🤗 Transformers fornecem uma maneira simples e unificada de carregar instâncias pré-treinadas. Isso significa que você pode carregar um [`TFAutoModel`] como carregaria um [`AutoTokenizer`]. A única diferença é selecionar o [`TFAutoModel`] correto para a tarefa. Como você está fazendo classificação de texto ou sequência, carregue [`TFAutoModelForSequenceClassification`]:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+Veja o [sumário de tarefas](./task_summary) para qual classe de [`AutoModel`] usar para cada tarefa.
+
+
+
+Agora você pode passar seu grupo de entradas pré-processadas diretamente para o modelo através da passagem de chaves de dicionários ao tensor.
+
+```py
+>>> tf_outputs = tf_model(tf_batch)
+```
+
+O modelo gera as ativações finais no atributo `logits`. Aplique a função softmax aos `logits` para recuperar as probabilidades:
+
+```py
+>>> import tensorflow as tf
+
+>>> tf_predictions = tf.nn.softmax(tf_outputs.logits, axis=-1)
+>>> tf_predictions # doctest: +IGNORE_RESULT
+```
+
+
+
+
+
+Todos os modelos de 🤗 Transformers (PyTorch ou TensorFlow) geram tensores *antes* da função de ativação final (como softmax) pois essa função algumas vezes é fundida com a perda.
+
+
+
+
+Os modelos são um standard [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) ou um [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) para que você possa usá-los em seu loop de treinamento habitual. No entanto, para facilitar as coisas, 🤗 Transformers fornece uma classe [`Trainer`] para PyTorch que adiciona funcionalidade para treinamento distribuído, precisão mista e muito mais. Para o TensorFlow, você pode usar o método `fit` de [Keras](https://keras.io/). Consulte o [tutorial de treinamento](./training) para obter mais detalhes.
+
+
+
+As saídas do modelo 🤗 Transformers são classes de dados especiais para que seus atributos sejam preenchidos automaticamente em um IDE.
+As saídas do modelo também se comportam como uma tupla ou um dicionário (por exemplo, você pode indexar com um inteiro, uma parte ou uma string), caso em que os atributos `None` são ignorados.
+
+
+
+### Salvar um modelo
+
+
+
+Uma vez que seu modelo estiver afinado, você pode salvá-lo com seu Tokenizer usando [`PreTrainedModel.save_pretrained`]:
+
+```py
+>>> pt_save_directory = "./pt_save_pretrained"
+>>> tokenizer.save_pretrained(pt_save_directory) # doctest: +IGNORE_RESULT
+>>> pt_model.save_pretrained(pt_save_directory)
+```
+
+Quando você estiver pronto para usá-lo novamente, recarregue com [`PreTrainedModel.from_pretrained`]:
+
+```py
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained("./pt_save_pretrained")
+```
+
+
+Uma vez que seu modelo estiver afinado, você pode salvá-lo com seu Tokenizer usando [`TFPreTrainedModel.save_pretrained`]:
+
+```py
+>>> tf_save_directory = "./tf_save_pretrained"
+>>> tokenizer.save_pretrained(tf_save_directory) # doctest: +IGNORE_RESULT
+>>> tf_model.save_pretrained(tf_save_directory)
+```
+
+Quando você estiver pronto para usá-lo novamente, recarregue com [`TFPreTrainedModel.from_pretrained`]
+
+```py
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("./tf_save_pretrained")
+```
+
+
+
+Um recurso particularmente interessante dos 🤗 Transformers é a capacidade de salvar um modelo e recarregá-lo como um modelo PyTorch ou TensorFlow. Use `from_pt` ou `from_tf` para converter o modelo de um framework para outro:
+
+
+
+
+```py
+>>> from transformers import AutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(pt_save_directory)
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(pt_save_directory, from_pt=True)
+```
+
+
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(tf_save_directory)
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(tf_save_directory, from_tf=True)
+```
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/run_scripts.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/run_scripts.md
new file mode 100644
index 0000000000000000000000000000000000000000..d4cc3973608d2c692244fd809174a216446dc294
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/run_scripts.md
@@ -0,0 +1,354 @@
+
+
+# Treinamento a partir de um script
+
+Junto com os 🤗 Transformers [notebooks](./notebooks), também há scripts de exemplo demonstrando como treinar um modelo para uma tarefa com [PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch), [TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow) ou [JAX/Flax](https://github.com/huggingface/transformers/tree/main/examples/flax).
+
+Você também encontrará scripts que usamos em nossos [projetos de pesquisa](https://github.com/huggingface/transformers/tree/main/examples/research_projects) e [exemplos legados](https://github.com/huggingface/transformers/tree/main/examples/legacy) que são principalmente contribuições da comunidade. Esses scripts não são mantidos ativamente e exigem uma versão específica de 🤗 Transformers que provavelmente será incompatível com a versão mais recente da biblioteca.
+
+Não se espera que os scripts de exemplo funcionem imediatamente em todos os problemas, você pode precisar adaptar o script ao problema que está tentando resolver. Para ajudá-lo com isso, a maioria dos scripts expõe totalmente como os dados são pré-processados, permitindo que você os edite conforme necessário para seu caso de uso.
+
+Para qualquer recurso que você gostaria de implementar em um script de exemplo, discuta-o no [fórum](https://discuss.huggingface.co/) ou em uma [issue](https://github.com/huggingface/transformers/issues) antes de enviar um Pull Request. Embora recebamos correções de bugs, é improvável que mesclaremos um Pull Request que adicione mais funcionalidades ao custo de legibilidade.
+
+Este guia mostrará como executar um exemplo de script de treinamento de sumarização em [PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization) e [TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/summarization). Espera-se que todos os exemplos funcionem com ambas as estruturas, a menos que especificado de outra forma.
+
+## Configuração
+
+Para executar com êxito a versão mais recente dos scripts de exemplo, você precisa **instalar o 🤗 Transformers da fonte** em um novo ambiente virtual:
+
+```bash
+git clone https://github.com/huggingface/transformers
+cd transformers
+pip install .
+```
+
+Para versões mais antigas dos scripts de exemplo, clique no botão abaixo:
+
+
+ Exemplos para versões antigas dos 🤗 Transformers
+
+
+
+Em seguida, mude seu clone atual dos 🤗 Transformers para uma versão específica, como v3.5.1, por exemplo:
+
+```bash
+git checkout tags/v3.5.1
+```
+
+Depois de configurar a versão correta da biblioteca, navegue até a pasta de exemplo de sua escolha e instale os requisitos específicos do exemplo:
+
+```bash
+pip install -r requirements.txt
+```
+
+## Executando um script
+
+
+
+
+O script de exemplo baixa e pré-processa um conjunto de dados da biblioteca 🤗 [Datasets](https://huggingface.co/docs/datasets/). Em seguida, o script ajusta um conjunto de dados com o [Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) em uma arquitetura que oferece suporte à sumarização. O exemplo a seguir mostra como ajustar [T5-small](https://huggingface.co/google-t5/t5-small) no conjunto de dados [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail). O modelo T5 requer um argumento `source_prefix` adicional devido à forma como foi treinado. Este prompt informa ao T5 que esta é uma tarefa de sumarização.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+Este outro script de exemplo baixa e pré-processa um conjunto de dados da biblioteca 🤗 [Datasets](https://huggingface.co/docs/datasets/). Em seguida, o script ajusta um conjunto de dados usando Keras em uma arquitetura que oferece suporte à sumarização. O exemplo a seguir mostra como ajustar [T5-small](https://huggingface.co/google-t5/t5-small) no conjunto de dados [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail). O modelo T5 requer um argumento `source_prefix` adicional devido à forma como foi treinado. Este prompt informa ao T5 que esta é uma tarefa de sumarização.
+
+```bash
+python examples/tensorflow/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## Treinamento distribuído e precisão mista
+
+O [Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) oferece suporte a treinamento distribuído e precisão mista, o que significa que você também pode usá-lo em um script. Para habilitar esses dois recursos:
+
+- Adicione o argumento `fp16` para habilitar a precisão mista.
+- Defina o número de GPUs a serem usadas com o argumento `nproc_per_node`.
+
+```bash
+torchrun \
+ --nproc_per_node 8 pytorch/summarization/run_summarization.py \
+ --fp16 \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+Os scripts do TensorFlow utilizam um [`MirroredStrategy`](https://www.tensorflow.org/guide/distributed_training#mirroredstrategy) para treinamento distribuído, e você não precisa adicionar argumentos adicionais ao script de treinamento. O script do TensorFlow usará várias GPUs por padrão, se estiverem disponíveis.
+
+## Executando um script em uma TPU
+
+
+
+As Unidades de Processamento de Tensor (TPUs) são projetadas especificamente para acelerar o desempenho. O PyTorch oferece suporte a TPUs com o compilador de aprendizado profundo [XLA](https://www.tensorflow.org/xla) (consulte [aqui](https://github.com/pytorch/xla/blob/master/README.md) para mais detalhes). Para usar uma TPU, inicie o script `xla_spawn.py` e use o argumento `num_cores` para definir o número de núcleos de TPU que você deseja usar.
+
+```bash
+python xla_spawn.py --num_cores 8 \
+ summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+
+As Unidades de Processamento de Tensor (TPUs) são projetadas especificamente para acelerar o desempenho. Os scripts do TensorFlow utilizam uma [`TPUStrategy`](https://www.tensorflow.org/guide/distributed_training#tpustrategy) para treinamento em TPUs. Para usar uma TPU, passe o nome do recurso TPU para o argumento `tpu`.
+
+```bash
+python run_summarization.py \
+ --tpu name_of_tpu_resource \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## Execute um script com 🤗 Accelerate
+
+🤗 [Accelerate](https://huggingface.co/docs/accelerate) é uma biblioteca somente do PyTorch que oferece um método unificado para treinar um modelo em vários tipos de configurações (CPU, multiplas GPUs, TPUs), mantendo visibilidade no loop de treinamento do PyTorch. Certifique-se de ter o 🤗 Accelerate instalado se ainda não o tiver:
+
+> Nota: Como o Accelerate está se desenvolvendo rapidamente, a versão git do Accelerate deve ser instalada para executar os scripts
+
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+Em vez do script `run_summarization.py`, você precisa usar o script `run_summarization_no_trainer.py`. Os scripts suportados pelo 🤗 Accelerate terão um arquivo `task_no_trainer.py` na pasta. Comece executando o seguinte comando para criar e salvar um arquivo de configuração:
+
+```bash
+accelerate config
+```
+
+Teste sua configuração para garantir que ela esteja corretamente configurada :
+
+```bash
+accelerate test
+```
+
+Agora você está pronto para iniciar o treinamento:
+
+```bash
+accelerate launch run_summarization_no_trainer.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir ~/tmp/tst-summarization
+```
+
+## Usando um conjunto de dados personalizado
+
+O script de resumo oferece suporte a conjuntos de dados personalizados, desde que sejam um arquivo CSV ou JSON. Ao usar seu próprio conjunto de dados, você precisa especificar vários argumentos adicionais:
+
+- `train_file` e `validation_file` especificam o caminho para seus arquivos de treinamento e validação respectivamente.
+- `text_column` é o texto de entrada para sumarização.
+- `summary_column` é o texto de destino para saída.
+
+Um script para sumarização usando um conjunto de dados customizado ficaria assim:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --train_file path_to_csv_or_jsonlines_file \
+ --validation_file path_to_csv_or_jsonlines_file \
+ --text_column text_column_name \
+ --summary_column summary_column_name \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --overwrite_output_dir \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --predict_with_generate
+```
+
+## Testando um script
+
+Geralmente, é uma boa ideia executar seu script em um número menor de exemplos de conjuntos de dados para garantir que tudo funcione conforme o esperado antes de se comprometer com um conjunto de dados inteiro, que pode levar horas para ser concluído. Use os seguintes argumentos para truncar o conjunto de dados para um número máximo de amostras:
+
+- `max_train_samples`
+- `max_eval_samples`
+- `max_predict_samples`
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --max_train_samples 50 \
+ --max_eval_samples 50 \
+ --max_predict_samples 50 \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+Nem todos os scripts de exemplo suportam o argumento `max_predict_samples`. Se você não tiver certeza se seu script suporta este argumento, adicione o argumento `-h` para verificar:
+
+```bash
+examples/pytorch/summarization/run_summarization.py -h
+```
+
+## Retomar o treinamento a partir de um checkpoint
+
+Outra opção útil para habilitar é retomar o treinamento de um checkpoint anterior. Isso garantirá que você possa continuar de onde parou sem recomeçar se o seu treinamento for interrompido. Existem dois métodos para retomar o treinamento a partir de um checkpoint.
+
+O primeiro método usa o argumento `output_dir previous_output_dir` para retomar o treinamento do último checkpoint armazenado em `output_dir`. Neste caso, você deve remover `overwrite_output_dir`:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --output_dir previous_output_dir \
+ --predict_with_generate
+```
+
+O segundo método usa o argumento `resume_from_checkpoint path_to_specific_checkpoint` para retomar o treinamento de uma pasta de checkpoint específica.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --resume_from_checkpoint path_to_specific_checkpoint \
+ --predict_with_generate
+```
+
+## Compartilhando seu modelo
+
+Todos os scripts podem enviar seu modelo final para o [Model Hub](https://huggingface.co/models). Certifique-se de estar conectado ao Hugging Face antes de começar:
+
+```bash
+huggingface-cli login
+```
+
+Em seguida, adicione o argumento `push_to_hub` ao script. Este argumento criará um repositório com seu nome de usuário do Hugging Face e o nome da pasta especificado em `output_dir`.
+
+Para dar um nome específico ao seu repositório, use o argumento `push_to_hub_model_id` para adicioná-lo. O repositório será listado automaticamente em seu namespace.
+
+O exemplo a seguir mostra como fazer upload de um modelo com um nome de repositório específico:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --push_to_hub \
+ --push_to_hub_model_id finetuned-t5-cnn_dailymail \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/serialization.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/serialization.md
new file mode 100644
index 0000000000000000000000000000000000000000..9e390f07bde41ded4d80a6d8faf75d563c3a2457
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/serialization.md
@@ -0,0 +1,502 @@
+
+
+# Exportando modelos para ONNX
+
+Se você precisar implantar modelos 🤗 Transformers em ambientes de produção, recomendamos
+exporta-los para um formato serializado que pode ser carregado e executado em
+tempos de execução e hardware. Neste guia, mostraremos como exportar modelos 🤗 Transformers
+para [ONNX (Open Neural Network eXchange)](http://onnx.ai).
+
+
+
+Uma vez exportado, um modelo pode ser otimizado para inferência por meio de técnicas como
+quantização e poda. Se você estiver interessado em otimizar seus modelos para serem executados com
+máxima eficiência, confira a biblioteca [🤗 Optimum
+](https://github.com/huggingface/optimum).
+
+
+
+ONNX é um padrão aberto que define um conjunto comum de operadores e um formato de arquivo comum
+para representar modelos de aprendizado profundo em uma ampla variedade de estruturas, incluindo PyTorch e
+TensorFlow. Quando um modelo é exportado para o formato ONNX, esses operadores são usados para
+construir um grafo computacional (muitas vezes chamado de _representação intermediária_) que
+representa o fluxo de dados através da rede neural.
+
+Ao expor um grafo com operadores e tipos de dados padronizados, o ONNX facilita a
+alternar entre os frameworks. Por exemplo, um modelo treinado em PyTorch pode ser exportado para
+formato ONNX e depois importado no TensorFlow (e vice-versa).
+
+🤗 Transformers fornece um pacote [`transformers.onnx`](main_classes/onnx) que permite
+que você converta os checkpoints do modelo em um grafo ONNX aproveitando os objetos de configuração.
+Esses objetos de configuração vêm prontos para várias arquiteturas de modelo e são
+projetado para ser facilmente extensível a outras arquiteturas.
+
+As configurações prontas incluem as seguintes arquiteturas:
+
+
+
+- ALBERT
+- BART
+- BEiT
+- BERT
+- BigBird
+- BigBird-Pegasus
+- Blenderbot
+- BlenderbotSmall
+- BLOOM
+- CamemBERT
+- CLIP
+- CodeGen
+- Conditional DETR
+- ConvBERT
+- ConvNeXT
+- ConvNeXTV2
+- Data2VecText
+- Data2VecVision
+- DeBERTa
+- DeBERTa-v2
+- DeiT
+- DETR
+- DistilBERT
+- ELECTRA
+- ERNIE
+- FlauBERT
+- GPT Neo
+- GPT-J
+- GroupViT
+- I-BERT
+- LayoutLM
+- LayoutLMv3
+- LeViT
+- Longformer
+- LongT5
+- M2M100
+- Marian
+- mBART
+- MobileBERT
+- MobileViT
+- MT5
+- OpenAI GPT-2
+- OWL-ViT
+- Perceiver
+- PLBart
+- ResNet
+- RoBERTa
+- RoFormer
+- SegFormer
+- SqueezeBERT
+- Swin Transformer
+- T5
+- Table Transformer
+- Vision Encoder decoder
+- ViT
+- XLM
+- XLM-RoBERTa
+- XLM-RoBERTa-XL
+- YOLOS
+
+Nas próximas duas seções, mostraremos como:
+
+* Exportar um modelo suportado usando o pacote `transformers.onnx`.
+* Exportar um modelo personalizado para uma arquitetura sem suporte.
+
+## Exportando um modelo para ONNX
+
+Para exportar um modelo 🤗 Transformers para o ONNX, primeiro você precisa instalar algumas
+dependências extras:
+
+```bash
+pip install transformers[onnx]
+```
+
+O pacote `transformers.onnx` pode então ser usado como um módulo Python:
+
+```bash
+python -m transformers.onnx --help
+
+usage: Hugging Face Transformers ONNX exporter [-h] -m MODEL [--feature {causal-lm, ...}] [--opset OPSET] [--atol ATOL] output
+
+positional arguments:
+ output Path indicating where to store generated ONNX model.
+
+optional arguments:
+ -h, --help show this help message and exit
+ -m MODEL, --model MODEL
+ Model ID on huggingface.co or path on disk to load model from.
+ --feature {causal-lm, ...}
+ The type of features to export the model with.
+ --opset OPSET ONNX opset version to export the model with.
+ --atol ATOL Absolute difference tolerance when validating the model.
+```
+
+A exportação de um checkpoint usando uma configuração pronta pode ser feita da seguinte forma:
+
+```bash
+python -m transformers.onnx --model=distilbert/distilbert-base-uncased onnx/
+```
+
+Você deve ver os seguintes logs:
+
+```bash
+Validating ONNX model...
+ -[✓] ONNX model output names match reference model ({'last_hidden_state'})
+ - Validating ONNX Model output "last_hidden_state":
+ -[✓] (2, 8, 768) matches (2, 8, 768)
+ -[✓] all values close (atol: 1e-05)
+All good, model saved at: onnx/model.onnx
+```
+
+Isso exporta um grafo ONNX do ponto de verificação definido pelo argumento `--model`. Nisso
+Por exemplo, é `distilbert/distilbert-base-uncased`, mas pode ser qualquer checkpoint no Hugging
+Face Hub ou um armazenado localmente.
+
+O arquivo `model.onnx` resultante pode ser executado em um dos [muitos
+aceleradores](https://onnx.ai/supported-tools.html#deployModel) que suportam o ONNX
+padrão. Por exemplo, podemos carregar e executar o modelo com [ONNX
+Tempo de execução](https://onnxruntime.ai/) da seguinte forma:
+
+```python
+>>> from transformers import AutoTokenizer
+>>> from onnxruntime import InferenceSession
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> session = InferenceSession("onnx/model.onnx")
+>>> # ONNX Runtime expects NumPy arrays as input
+>>> inputs = tokenizer("Using DistilBERT with ONNX Runtime!", return_tensors="np")
+>>> outputs = session.run(output_names=["last_hidden_state"], input_feed=dict(inputs))
+```
+
+Os nomes de saída necessários (como `["last_hidden_state"]`) podem ser obtidos pegando uma
+ configuração ONNX de cada modelo. Por exemplo, para DistilBERT temos:
+
+```python
+>>> from transformers.models.distilbert import DistilBertConfig, DistilBertOnnxConfig
+
+>>> config = DistilBertConfig()
+>>> onnx_config = DistilBertOnnxConfig(config)
+>>> print(list(onnx_config.outputs.keys()))
+["last_hidden_state"]
+```
+
+O processo é idêntico para os checkpoints do TensorFlow no Hub. Por exemplo, podemos
+exportar um checkpoint TensorFlow puro do [Keras
+](https://huggingface.co/keras-io) da seguinte forma:
+
+```bash
+python -m transformers.onnx --model=keras-io/transformers-qa onnx/
+```
+
+Para exportar um modelo armazenado localmente, você precisará ter os pesos e
+arquivos tokenizer armazenados em um diretório. Por exemplo, podemos carregar e salvar um checkpoint como:
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> # Load tokenizer and PyTorch weights form the Hub
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+>>> # Save to disk
+>>> tokenizer.save_pretrained("local-pt-checkpoint")
+>>> pt_model.save_pretrained("local-pt-checkpoint")
+```
+
+Uma vez que o checkpoint é salvo, podemos exportá-lo para o ONNX apontando o `--model`
+argumento do pacote `transformers.onnx` para o diretório desejado:
+
+```bash
+python -m transformers.onnx --model=local-pt-checkpoint onnx/
+```
+
+```python
+>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
+
+>>> # Load tokenizer and TensorFlow weights from the Hub
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+>>> # Save to disk
+>>> tokenizer.save_pretrained("local-tf-checkpoint")
+>>> tf_model.save_pretrained("local-tf-checkpoint")
+```
+
+Uma vez que o checkpoint é salvo, podemos exportá-lo para o ONNX apontando o `--model`
+argumento do pacote `transformers.onnx` para o diretório desejado:
+
+```bash
+python -m transformers.onnx --model=local-tf-checkpoint onnx/
+```
+
+## Selecionando features para diferentes tarefas do modelo
+
+Cada configuração pronta vem com um conjunto de _features_ que permitem exportar
+modelos para diferentes tipos de tarefas. Conforme mostrado na tabela abaixo, cada recurso é
+associado a uma `AutoClass` diferente:
+
+| Feature | Auto Class |
+| ------------------------------------ | ------------------------------------ |
+| `causal-lm`, `causal-lm-with-past` | `AutoModelForCausalLM` |
+| `default`, `default-with-past` | `AutoModel` |
+| `masked-lm` | `AutoModelForMaskedLM` |
+| `question-answering` | `AutoModelForQuestionAnswering` |
+| `seq2seq-lm`, `seq2seq-lm-with-past` | `AutoModelForSeq2SeqLM` |
+| `sequence-classification` | `AutoModelForSequenceClassification` |
+| `token-classification` | `AutoModelForTokenClassification` |
+
+Para cada configuração, você pode encontrar a lista de recursos suportados por meio do
+[`~transformers.onnx.FeaturesManager`]. Por exemplo, para DistilBERT temos:
+
+```python
+>>> from transformers.onnx.features import FeaturesManager
+
+>>> distilbert_features = list(FeaturesManager.get_supported_features_for_model_type("distilbert").keys())
+>>> print(distilbert_features)
+["default", "masked-lm", "causal-lm", "sequence-classification", "token-classification", "question-answering"]
+```
+
+Você pode então passar um desses recursos para o argumento `--feature` no
+pacote `transformers.onnx`. Por exemplo, para exportar um modelo de classificação de texto, podemos
+escolher um modelo ajustado no Hub e executar:
+
+```bash
+python -m transformers.onnx --model=distilbert/distilbert-base-uncased-finetuned-sst-2-english \
+ --feature=sequence-classification onnx/
+```
+
+Isso exibe os seguintes logs:
+
+```bash
+Validating ONNX model...
+ -[✓] ONNX model output names match reference model ({'logits'})
+ - Validating ONNX Model output "logits":
+ -[✓] (2, 2) matches (2, 2)
+ -[✓] all values close (atol: 1e-05)
+All good, model saved at: onnx/model.onnx
+```
+
+Observe que, neste caso, os nomes de saída do modelo ajustado são `logits`
+em vez do `last_hidden_state` que vimos com o checkpoint `distilbert/distilbert-base-uncased`
+mais cedo. Isso é esperado, pois o modelo ajustado (fine-tuned) possui uma cabeça de classificação de sequência.
+
+
+
+Os recursos que têm um sufixo `with-pass` (como `causal-lm-with-pass`) correspondem a
+classes de modelo com estados ocultos pré-computados (chave e valores nos blocos de atenção)
+que pode ser usado para decodificação autorregressiva rápida.
+
+
+
+
+
+Para modelos do tipo `VisionEncoderDecoder`, as partes do codificador e do decodificador são
+exportados separadamente como dois arquivos ONNX chamados `encoder_model.onnx` e `decoder_model.onnx` respectivamente.
+
+
+
+## Exportando um modelo para uma arquitetura sem suporte
+
+Se você deseja exportar um modelo cuja arquitetura não é suportada nativamente pela
+biblioteca, há três etapas principais a seguir:
+
+1. Implemente uma configuração ONNX personalizada.
+2. Exporte o modelo para o ONNX.
+3. Valide as saídas do PyTorch e dos modelos exportados.
+
+Nesta seção, veremos como o DistilBERT foi implementado para mostrar o que está envolvido
+em cada passo.
+
+### Implementando uma configuração ONNX personalizada
+
+Vamos começar com o objeto de configuração ONNX. Fornecemos três classes abstratas que
+você deve herdar, dependendo do tipo de arquitetura de modelo que deseja exportar:
+
+* Modelos baseados em codificador herdam de [`~onnx.config.OnnxConfig`]
+* Modelos baseados em decodificador herdam de [`~onnx.config.OnnxConfigWithPast`]
+* Os modelos codificador-decodificador herdam de [`~onnx.config.OnnxSeq2SeqConfigWithPast`]
+
+
+
+Uma boa maneira de implementar uma configuração ONNX personalizada é observar as
+implementação no arquivo `configuration_.py` de uma arquitetura semelhante.
+
+
+
+Como o DistilBERT é um modelo baseado em codificador, sua configuração é herdada de
+`OnnxConfig`:
+
+```python
+>>> from typing import Mapping, OrderedDict
+>>> from transformers.onnx import OnnxConfig
+
+
+>>> class DistilBertOnnxConfig(OnnxConfig):
+... @property
+... def inputs(self) -> Mapping[str, Mapping[int, str]]:
+... return OrderedDict(
+... [
+... ("input_ids", {0: "batch", 1: "sequence"}),
+... ("attention_mask", {0: "batch", 1: "sequence"}),
+... ]
+... )
+```
+
+Todo objeto de configuração deve implementar a propriedade `inputs` e retornar um mapeamento,
+onde cada chave corresponde a uma entrada esperada e cada valor indica o eixo
+dessa entrada. Para o DistilBERT, podemos ver que duas entradas são necessárias: `input_ids` e
+`attention_mask`. Essas entradas têm a mesma forma de `(batch_size, sequence_length)`
+é por isso que vemos os mesmos eixos usados na configuração.
+
+
+
+Notice that `inputs` property for `DistilBertOnnxConfig` returns an `OrderedDict`. This
+ensures that the inputs are matched with their relative position within the
+`PreTrainedModel.forward()` method when tracing the graph. We recommend using an
+`OrderedDict` for the `inputs` and `outputs` properties when implementing custom ONNX
+configurations.
+
+Observe que a propriedade `inputs` para `DistilBertOnnxConfig` retorna um `OrderedDict`. Este
+garante que as entradas sejam combinadas com sua posição relativa dentro do
+método `PreTrainedModel.forward()` ao traçar o grafo. Recomendamos o uso de um
+`OrderedDict` para as propriedades `inputs` e `outputs` ao implementar configurações personalizadas ONNX.
+
+
+
+Depois de implementar uma configuração ONNX, você pode instanciá-la fornecendo a
+configuração do modelo base da seguinte forma:
+
+```python
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased")
+>>> onnx_config = DistilBertOnnxConfig(config)
+```
+
+O objeto resultante tem várias propriedades úteis. Por exemplo, você pode visualizar o conjunto de operadores ONNX
+ que será usado durante a exportação:
+
+```python
+>>> print(onnx_config.default_onnx_opset)
+11
+```
+
+Você também pode visualizar as saídas associadas ao modelo da seguinte forma:
+
+```python
+>>> print(onnx_config.outputs)
+OrderedDict([("last_hidden_state", {0: "batch", 1: "sequence"})])
+```
+
+Observe que a propriedade outputs segue a mesma estrutura das entradas; ele retorna um
+`OrderedDict` de saídas nomeadas e suas formas. A estrutura de saída está ligada a
+escolha do recurso com o qual a configuração é inicializada. Por padrão, a configuração do ONNX
+é inicializada com o recurso `default` que corresponde à exportação de um
+modelo carregado com a classe `AutoModel`. Se você deseja exportar um modelo para outra tarefa,
+apenas forneça um recurso diferente para o argumento `task` quando você inicializar a configuração ONNX
+. Por exemplo, se quisermos exportar o DistilBERT com uma sequência
+de classificação, poderíamos usar:
+
+```python
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased")
+>>> onnx_config_for_seq_clf = DistilBertOnnxConfig(config, task="sequence-classification")
+>>> print(onnx_config_for_seq_clf.outputs)
+OrderedDict([('logits', {0: 'batch'})])
+```
+
+
+
+Todas as propriedades e métodos básicos associados a [`~onnx.config.OnnxConfig`] e
+as outras classes de configuração podem ser substituídas se necessário. Confira [`BartOnnxConfig`]
+para um exemplo avançado.
+
+
+
+### Exportando um modelo
+
+Depois de ter implementado a configuração do ONNX, o próximo passo é exportar o modelo.
+Aqui podemos usar a função `export()` fornecida pelo pacote `transformers.onnx`.
+Esta função espera a configuração do ONNX, juntamente com o modelo base e o tokenizer,
+e o caminho para salvar o arquivo exportado:
+
+```python
+>>> from pathlib import Path
+>>> from transformers.onnx import export
+>>> from transformers import AutoTokenizer, AutoModel
+
+>>> onnx_path = Path("model.onnx")
+>>> model_ckpt = "distilbert/distilbert-base-uncased"
+>>> base_model = AutoModel.from_pretrained(model_ckpt)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_ckpt)
+
+>>> onnx_inputs, onnx_outputs = export(tokenizer, base_model, onnx_config, onnx_config.default_onnx_opset, onnx_path)
+```
+
+Os `onnx_inputs` e `onnx_outputs` retornados pela função `export()` são listas de
+ chaves definidas nas propriedades `inputs` e `outputs` da configuração. Uma vez que o
+modelo é exportado, você pode testar se o modelo está bem formado da seguinte forma:
+
+```python
+>>> import onnx
+
+>>> onnx_model = onnx.load("model.onnx")
+>>> onnx.checker.check_model(onnx_model)
+```
+
+
+
+Se o seu modelo for maior que 2GB, você verá que muitos arquivos adicionais são criados
+durante a exportação. Isso é _esperado_ porque o ONNX usa [Protocol
+Buffers](https://developers.google.com/protocol-buffers/) para armazenar o modelo e estes
+têm um limite de tamanho de 2GB. Veja a [ONNX
+documentação](https://github.com/onnx/onnx/blob/master/docs/ExternalData.md) para
+instruções sobre como carregar modelos com dados externos.
+
+
+
+### Validando a saída dos modelos
+
+A etapa final é validar se as saídas do modelo base e exportado concordam
+dentro de alguma tolerância absoluta. Aqui podemos usar a função `validate_model_outputs()`
+fornecida pelo pacote `transformers.onnx` da seguinte forma:
+
+```python
+>>> from transformers.onnx import validate_model_outputs
+
+>>> validate_model_outputs(
+... onnx_config, tokenizer, base_model, onnx_path, onnx_outputs, onnx_config.atol_for_validation
+... )
+```
+
+Esta função usa o método [`~transformers.onnx.OnnxConfig.generate_dummy_inputs`] para
+gerar entradas para o modelo base e o exportado, e a tolerância absoluta pode ser
+definida na configuração. Geralmente encontramos concordância numérica em 1e-6 a 1e-4
+de alcance, embora qualquer coisa menor que 1e-3 provavelmente esteja OK.
+
+## Contribuindo com uma nova configuração para 🤗 Transformers
+
+Estamos procurando expandir o conjunto de configurações prontas e receber contribuições
+da comunidade! Se você gostaria de contribuir para a biblioteca, você
+precisará:
+
+* Implemente a configuração do ONNX no arquivo `configuration_.py` correspondente
+Arquivo
+* Incluir a arquitetura do modelo e recursos correspondentes em
+ [`~onnx.features.FeatureManager`]
+* Adicione sua arquitetura de modelo aos testes em `test_onnx_v2.py`
+
+Confira como ficou a configuração do [IBERT
+](https://github.com/huggingface/transformers/pull/14868/files) para obter uma
+idéia do que está envolvido.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/tasks/sequence_classification.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/tasks/sequence_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..a2e6865c92e5b619d2427c972bf54122dfcc9096
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/tasks/sequence_classification.md
@@ -0,0 +1,216 @@
+
+
+# Classificação de texto
+
+
+
+Consulte a [página de tarefas de classificação de texto](https://huggingface.co/tasks/text-classification) para obter mais informações sobre outras formas de classificação de texto e seus modelos, conjuntos de dados e métricas associados.
+
+
+
+## Carregue o conjunto de dados IMDb
+
+Carregue o conjunto de dados IMDb utilizando a biblioteca 🤗 Datasets:
+
+```py
+>>> from datasets import load_dataset
+
+>>> imdb = load_dataset("imdb")
+```
+
+Em seguida, dê uma olhada em um exemplo:
+
+```py
+>>> imdb["test"][0]
+{
+ "label": 0,
+ "text": "I love sci-fi and am willing to put up with a lot. Sci-fi movies/TV are usually underfunded, under-appreciated and misunderstood. I tried to like this, I really did, but it is to good TV sci-fi as Babylon 5 is to Star Trek (the original). Silly prosthetics, cheap cardboard sets, stilted dialogues, CG that doesn't match the background, and painfully one-dimensional characters cannot be overcome with a 'sci-fi' setting. (I'm sure there are those of you out there who think Babylon 5 is good sci-fi TV. It's not. It's clichéd and uninspiring.) While US viewers might like emotion and character development, sci-fi is a genre that does not take itself seriously (cf. Star Trek). It may treat important issues, yet not as a serious philosophy. It's really difficult to care about the characters here as they are not simply foolish, just missing a spark of life. Their actions and reactions are wooden and predictable, often painful to watch. The makers of Earth KNOW it's rubbish as they have to always say \"Gene Roddenberry's Earth...\" otherwise people would not continue watching. Roddenberry's ashes must be turning in their orbit as this dull, cheap, poorly edited (watching it without advert breaks really brings this home) trudging Trabant of a show lumbers into space. Spoiler. So, kill off a main character. And then bring him back as another actor. Jeeez! Dallas all over again.",
+}
+```
+
+Existem dois campos neste dataset:
+
+- `text`: uma string contendo o texto da crítica do filme.
+- `label`: um valor que pode ser `0` para uma crítica negativa ou `1` para uma crítica positiva.
+
+## Pré-processamento dos dados
+
+Carregue o tokenizador do DistilBERT para processar o campo `text`:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Crie uma função de pré-processamento para tokenizar o campo `text` e truncar as sequências para que não sejam maiores que o comprimento máximo de entrada do DistilBERT:
+
+```py
+>>> def preprocess_function(examples):
+... return tokenizer(examples["text"], truncation=True)
+```
+
+Use a função [`map`](https://huggingface.co/docs/datasets/process#map) do 🤗 Datasets para aplicar a função de pré-processamento em todo o conjunto de dados. Você pode acelerar a função `map` definindo `batched=True` para processar vários elementos do conjunto de dados de uma só vez:
+
+```py
+tokenized_imdb = imdb.map(preprocess_function, batched=True)
+```
+
+Use o [`DataCollatorWithPadding`] para criar um batch de exemplos. Ele também *preencherá dinamicamente* seu texto até o comprimento do elemento mais longo em seu batch, para que os exemplos do batch tenham um comprimento uniforme. Embora seja possível preencher seu texto com a função `tokenizer` definindo `padding=True`, o preenchimento dinâmico utilizando um data collator é mais eficiente.
+
+
+
+```py
+>>> from transformers import DataCollatorWithPadding
+
+>>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
+```
+
+
+```py
+>>> from transformers import DataCollatorWithPadding
+
+>>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer, return_tensors="tf")
+```
+
+
+
+## Train
+
+
+
+Carregue o DistilBERT com [`AutoModelForSequenceClassification`] junto com o número de rótulos esperados:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased", num_labels=2)
+```
+
+
+
+Se você não estiver familiarizado com o fine-tuning de um modelo com o [`Trainer`], dê uma olhada no tutorial básico [aqui](../training#finetune-with-trainer)!
+
+
+
+Nesse ponto, restam apenas três passos:
+
+1. Definir seus hiperparâmetros de treinamento em [`TrainingArguments`].
+2. Passar os argumentos de treinamento para o [`Trainer`] junto com o modelo, conjunto de dados, tokenizador e o data collator.
+3. Chamar a função [`~Trainer.train`] para executar o fine-tuning do seu modelo.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="./results",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=5,
+... weight_decay=0.01,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_imdb["train"],
+... eval_dataset=tokenized_imdb["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+
+
+O [`Trainer`] aplicará o preenchimento dinâmico por padrão quando você definir o argumento `tokenizer` dele. Nesse caso, você não precisa especificar um data collator explicitamente.
+
+
+
+
+Para executar o fine-tuning de um modelo no TensorFlow, comece convertendo seu conjunto de dados para o formato `tf.data.Dataset` com [`to_tf_dataset`](https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Dataset.to_tf_dataset). Nessa execução você deverá especificar as entradas e rótulos (no parâmetro `columns`), se deseja embaralhar o conjunto de dados, o tamanho do batch e o data collator:
+
+```py
+>>> tf_train_set = tokenized_imdb["train"].to_tf_dataset(
+... columns=["attention_mask", "input_ids", "label"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = tokenized_imdb["test"].to_tf_dataset(
+... columns=["attention_mask", "input_ids", "label"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+
+
+Se você não estiver familiarizado com o fine-tuning de um modelo com o Keras, dê uma olhada no tutorial básico [aqui](training#finetune-with-keras)!
+
+
+
+Configure o otimizador e alguns hiperparâmetros de treinamento:
+
+```py
+>>> from transformers import create_optimizer
+>>> import tensorflow as tf
+
+>>> batch_size = 16
+>>> num_epochs = 5
+>>> batches_per_epoch = len(tokenized_imdb["train"]) // batch_size
+>>> total_train_steps = int(batches_per_epoch * num_epochs)
+>>> optimizer, schedule = create_optimizer(init_lr=2e-5, num_warmup_steps=0, num_train_steps=total_train_steps)
+```
+
+Carregue o DistilBERT com [`TFAutoModelForSequenceClassification`] junto com o número de rótulos esperados:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased", num_labels=2)
+```
+
+Configure o modelo para treinamento com o método [`compile`](https://keras.io/api/models/model_training_apis/#compile-method):
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+Chame o método [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) para executar o fine-tuning do modelo:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3)
+```
+
+
+
+
+
+Para obter um exemplo mais aprofundado de como executar o fine-tuning de um modelo para classificação de texto, dê uma olhada nesse [notebook utilizando PyTorch](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification.ipynb) ou nesse [notebook utilizando TensorFlow](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification-tf.ipynb).
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/tasks/token_classification.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/tasks/token_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..45ce0d87429c58cf2f27b7b50666cb42df100ec4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/tasks/token_classification.md
@@ -0,0 +1,272 @@
+
+
+# Classificação de tokens
+
+
+
+Consulte a [página de tarefas de classificação de tokens](https://huggingface.co/tasks/token-classification) para obter mais informações sobre outras formas de classificação de tokens e seus modelos, conjuntos de dados e métricas associadas.
+
+
+
+## Carregando o conjunto de dados WNUT 17
+
+Carregue o conjunto de dados WNUT 17 da biblioteca 🤗 Datasets:
+
+```py
+>>> from datasets import load_dataset
+
+>>> wnut = load_dataset("wnut_17")
+```
+
+E dê uma olhada em um exemplo:
+
+```py
+>>> wnut["train"][0]
+{'id': '0',
+ 'ner_tags': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 7, 8, 8, 0, 7, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'tokens': ['@paulwalk', 'It', "'s", 'the', 'view', 'from', 'where', 'I', "'m", 'living', 'for', 'two', 'weeks', '.', 'Empire', 'State', 'Building', '=', 'ESB', '.', 'Pretty', 'bad', 'storm', 'here', 'last', 'evening', '.']
+}
+```
+
+Cada número em `ner_tags` representa uma entidade. Converta o número em um rótulo para obter mais informações:
+
+```py
+>>> label_list = wnut["train"].features[f"ner_tags"].feature.names
+>>> label_list
+[
+ "O",
+ "B-corporation",
+ "I-corporation",
+ "B-creative-work",
+ "I-creative-work",
+ "B-group",
+ "I-group",
+ "B-location",
+ "I-location",
+ "B-person",
+ "I-person",
+ "B-product",
+ "I-product",
+]
+```
+
+O `ner_tag` descreve uma entidade, como uma organização, local ou pessoa. A letra que prefixa cada `ner_tag` indica a posição do token da entidade:
+
+- `B-` indica o início de uma entidade.
+- `I-` indica que um token está contido dentro da mesma entidade (por exemplo, o token `State` pode fazer parte de uma entidade como `Empire State Building`).
+- `0` indica que o token não corresponde a nenhuma entidade.
+
+## Pré-processamento
+
+
+
+```py
+>>> from transformers import DataCollatorForTokenClassification
+
+>>> data_collator = DataCollatorForTokenClassification(tokenizer=tokenizer)
+```
+
+
+```py
+>>> from transformers import DataCollatorForTokenClassification
+
+>>> data_collator = DataCollatorForTokenClassification(tokenizer=tokenizer, return_tensors="tf")
+```
+
+
+
+## Treinamento
+
+
+
+Carregue o DistilBERT com o [`AutoModelForTokenClassification`] junto com o número de rótulos esperados:
+
+```py
+>>> from transformers import AutoModelForTokenClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased", num_labels=14)
+```
+
+
+
+Se você não estiver familiarizado com o fine-tuning de um modelo com o [`Trainer`], dê uma olhada no tutorial básico [aqui](../training#finetune-with-trainer)!
+
+
+
+Nesse ponto, restam apenas três passos:
+
+1. Definir seus hiperparâmetros de treinamento em [`TrainingArguments`].
+2. Passar os argumentos de treinamento para o [`Trainer`] junto com o modelo, conjunto de dados, tokenizador e o data collator.
+3. Chamar a função [`~Trainer.train`] para executar o fine-tuning do seu modelo.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="./results",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_wnut["train"],
+... eval_dataset=tokenized_wnut["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+
+Para executar o fine-tuning de um modelo no TensorFlow, comece convertendo seu conjunto de dados para o formato `tf.data.Dataset` com [`to_tf_dataset`](https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Dataset.to_tf_dataset). Nessa execução você deverá especificar as entradas e rótulos (no parâmetro `columns`), se deseja embaralhar o conjunto de dados, o tamanho do batch e o data collator:
+
+```py
+>>> tf_train_set = tokenized_wnut["train"].to_tf_dataset(
+... columns=["attention_mask", "input_ids", "labels"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = tokenized_wnut["validation"].to_tf_dataset(
+... columns=["attention_mask", "input_ids", "labels"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+
+
+Se você não estiver familiarizado com o fine-tuning de um modelo com o Keras, dê uma olhada no tutorial básico [aqui](training#finetune-with-keras)!
+
+
+
+Configure o otimizador e alguns hiperparâmetros de treinamento:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_train_epochs = 3
+>>> num_train_steps = (len(tokenized_wnut["train"]) // batch_size) * num_train_epochs
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=2e-5,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=0.01,
+... num_warmup_steps=0,
+... )
+```
+
+Carregue o DistilBERT com o [`TFAutoModelForTokenClassification`] junto com o número de rótulos esperados:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased", num_labels=2)
+```
+
+Configure o modelo para treinamento com o método [`compile`](https://keras.io/api/models/model_training_apis/#compile-method):
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+Chame o método [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) para executar o fine-tuning do modelo:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3)
+```
+
+
+
+
+
+Para obter um exemplo mais aprofundado de como executar o fine-tuning de um modelo para classificação de tokens, dê uma olhada nesse [notebook utilizando PyTorch](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification.ipynb) ou nesse [notebook utilizando TensorFlow](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification-tf.ipynb).
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/training.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/training.md
new file mode 100644
index 0000000000000000000000000000000000000000..67294baee35c1f8108ddfb65fdba2165c65e6ee2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/training.md
@@ -0,0 +1,416 @@
+
+
+# Fine-tuning de um modelo pré-treinado
+
+[[open-in-colab]]
+
+O uso de um modelo pré-treinado tem importantes vantagens. Redução do custo computacional, a pegada de carbono, e te
+permite utilizar modelos de última geração sem ter que treinar um novo desde o início.
+O 🤗 Transformers proporciona acesso a milhares de modelos pré-treinados numa ampla gama de tarefas.
+Quando utilizar um modelo pré-treinado, treine-o com um dataset específico para a sua tarefa.
+Isto é chamado de fine-tuning, uma técnica de treinamento incrivelmente poderosa. Neste tutorial faremos o fine-tuning
+de um modelo pré-treinado com um framework de Deep Learning da sua escolha:
+
+* Fine-tuning de um modelo pré-treinado com o 🤗 Transformers [`Trainer`].
+* Fine-tuning de um modelo pré-treinado no TensorFlow com o Keras.
+* Fine-tuning de um modelo pré-treinado em PyTorch nativo.
+
+
+
+ Você verá um alerta sobre alguns pesos pré-treinados que não estão sendo utilizados e que alguns pesos estão
+ sendo inicializados aleatoriamente. Não se preocupe, essa mensagem é completamente normal.
+ O header/cabeçário pré-treinado do modelo BERT é descartado e substitui-se por um header de classificação
+ inicializado aleatoriamente. Assim, pode aplicar o fine-tuning a este novo header do modelo em sua tarefa
+ de classificação de sequências fazendo um transfer learning do modelo pré-treinado.
+
+
+
+### Hiperparâmetros de treinamento
+
+Em seguida, crie uma classe [`TrainingArguments`] que contenha todos os hiperparâmetros que possam ser ajustados, assim
+como os indicadores para ativar as diferentes opções de treinamento. Para este tutorial, você pode começar o treinamento
+usando os [hiperparámetros](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments) padrão,
+porém, sinta-se livre para experimentar com eles e encontrar uma configuração ótima.
+
+Especifique onde salvar os checkpoints do treinamento:
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(output_dir="test_trainer")
+```
+
+### Métricas
+
+O [`Trainer`] não avalia automaticamente o rendimento do modelo durante o treinamento. Será necessário passar ao
+[`Trainer`] uma função para calcular e fazer um diagnóstico sobre as métricas. A biblioteca 🤗 Datasets proporciona
+uma função de [`accuracy`](https://huggingface.co/metrics/accuracy) simples que pode ser carregada com a função
+`load_metric` (ver este [tutorial](https://huggingface.co/docs/datasets/metrics) para mais informações):
+
+```py
+>>> import numpy as np
+>>> from datasets import load_metric
+
+>>> metric = load_metric("accuracy")
+```
+
+Defina a função `compute` dentro de `metric` para calcular a precisão das suas predições.
+Antes de passar as suas predições ao `compute`, é necessário converter as predições à logits (lembre-se que
+todos os modelos de 🤗 Transformers retornam logits).
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... predictions = np.argmax(logits, axis=-1)
+... return metric.compute(predictions=predictions, references=labels)
+```
+
+Se quiser controlar as suas métricas de avaliação durante o fine-tuning, especifique o parâmetro `eval_strategy`
+nos seus argumentos de treinamento para que o modelo considere a métrica de avaliação ao final de cada época:
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(output_dir="test_trainer", eval_strategy="epoch")
+```
+
+### Trainer
+
+Crie um objeto [`Trainer`] com o seu modelo, argumentos de treinamento, conjuntos de dados de treinamento e de teste, e a sua função de avaliação:
+
+```py
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=small_train_dataset,
+... eval_dataset=small_eval_dataset,
+... compute_metrics=compute_metrics,
+... )
+```
+
+Em seguida, aplique o fine-tuning a seu modelo chamado [`~transformers.Trainer.train`]:
+
+```py
+>>> trainer.train()
+```
+
+
+
+ O [`Trainer`] utiliza [`DataCollatorWithPadding`] por padrão, então você não precisa especificar explicitamente um
+ colador de dados (data collator).
+
+
+
+Em seguida, converta os datasets tokenizados em datasets do TensorFlow com o método
+[`to_tf_dataset`](https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Dataset.to_tf_dataset).
+Especifique suas entradas em `columns` e seu rótulo em `label_cols`:
+
+```py
+>>> tf_train_dataset = small_train_dataset.to_tf_dataset(
+... columns=["attention_mask", "input_ids", "token_type_ids"],
+... label_cols="labels",
+... shuffle=True,
+... collate_fn=data_collator,
+... batch_size=8,
+... )
+
+>>> tf_validation_dataset = small_eval_dataset.to_tf_dataset(
+... columns=["attention_mask", "input_ids", "token_type_ids"],
+... label_cols="labels",
+... shuffle=False,
+... collate_fn=data_collator,
+... batch_size=8,
+... )
+```
+
+### Compilação e ajustes
+
+Carregue um modelo do TensorFlow com o número esperado de rótulos:
+
+```py
+>>> import tensorflow as tf
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-cased", num_labels=5)
+```
+
+A seguir, compile e ajuste o fine-tuning a seu modelo com [`fit`](https://keras.io/api/models/model_training_apis/) como
+faria com qualquer outro modelo do Keras:
+
+```py
+>>> model.compile(
+... optimizer=tf.keras.optimizers.Adam(learning_rate=5e-5),
+... loss=tf.keras.losses.SparseCategoricalCrossentropy(from_logits=True),
+... metrics=tf.metrics.SparseCategoricalAccuracy(),
+... )
+
+>>> model.fit(tf_train_dataset, validation_data=tf_validation_dataset, epochs=3)
+```
+
+
+
+ Se necessário, você pode obter o acesso gratuito a uma GPU na núvem por meio de um notebook no
+ [Colaboratory](https://colab.research.google.com/) ou [SageMaker StudioLab](https://studiolab.sagemaker.aws/)
+ se não tiver esse recurso de forma local.
+
+
+
+Perfeito, agora estamos prontos para começar o treinamento! 🥳
+
+### Ciclo de treinamento
+
+Para visualizar melhor o processo de treinamento, utilize a biblioteca [tqdm](https://tqdm.github.io/) para adicionar
+uma barra de progresso sobre o número de passos percorridos no treinamento atual:
+
+```py
+>>> from tqdm.auto import tqdm
+
+>>> progress_bar = tqdm(range(num_training_steps))
+
+>>> model.train()
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... outputs = model(**batch)
+... loss = outputs.loss
+... loss.backward()
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+### Métricas
+
+Da mesma forma que é necessário adicionar uma função de avaliação ao [`Trainer`], é necessário fazer o mesmo quando
+escrevendo o próprio ciclo de treinamento. Contudo, em vez de calcular e retornar a métrica final de cada época,
+você deverá adicionar todos os batches com [`add_batch`](https://huggingface.co/docs/datasets/package_reference/main_classes?highlight=add_batch#datasets.Metric.add_batch)
+e calcular a métrica apenas no final.
+
+```py
+>>> metric = load_metric("accuracy")
+>>> model.eval()
+>>> for batch in eval_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... with torch.no_grad():
+... outputs = model(**batch)
+
+... logits = outputs.logits
+... predictions = torch.argmax(logits, dim=-1)
+... metric.add_batch(predictions=predictions, references=batch["labels"])
+
+>>> metric.compute()
+```
+
+
+
+
+## విషయాలు
+
+డాక్యుమెంటేషన్ ఐదు విభాగాలుగా నిర్వహించబడింది:
+
+- **ప్రారంభించండి** లైబ్రరీ యొక్క శీఘ్ర పర్యటన మరియు రన్నింగ్ కోసం ఇన్స్టాలేషన్ సూచనలను అందిస్తుంది.
+- **ట్యుటోరియల్స్** మీరు అనుభవశూన్యుడు అయితే ప్రారంభించడానికి గొప్ప ప్రదేశం. మీరు లైబ్రరీని ఉపయోగించడం ప్రారంభించడానికి అవసరమైన ప్రాథమిక నైపుణ్యాలను పొందడానికి ఈ విభాగం మీకు సహాయం చేస్తుంది.
+- **హౌ-టు-గైడ్లు** లాంగ్వేజ్ మోడలింగ్ కోసం ప్రిట్రైన్డ్ మోడల్ని ఫైన్ట్యూన్ చేయడం లేదా కస్టమ్ మోడల్ను ఎలా వ్రాయాలి మరియు షేర్ చేయాలి వంటి నిర్దిష్ట లక్ష్యాన్ని ఎలా సాధించాలో మీకు చూపుతాయి.
+- **కాన్సెప్చువల్ గైడ్స్** మోడల్లు, టాస్క్లు మరియు 🤗 ట్రాన్స్ఫార్మర్ల డిజైన్ ఫిలాసఫీ వెనుక ఉన్న అంతర్లీన భావనలు మరియు ఆలోచనల గురించి మరింత చర్చ మరియు వివరణను అందిస్తుంది.
+- **API** అన్ని తరగతులు మరియు విధులను వివరిస్తుంది:
+
+ - **ప్రధాన తరగతులు** కాన్ఫిగరేషన్, మోడల్, టోకెనైజర్ మరియు పైప్లైన్ వంటి అత్యంత ముఖ్యమైన తరగతులను వివరిస్తుంది.
+ - **మోడల్స్** లైబ్రరీలో అమలు చేయబడిన ప్రతి మోడల్కు సంబంధించిన తరగతులు మరియు విధులను వివరిస్తుంది.
+ - **అంతర్గత సహాయకులు** అంతర్గతంగా ఉపయోగించే యుటిలిటీ క్లాస్లు మరియు ఫంక్షన్ల వివరాలు.
+
+## మద్దతు ఉన్న నమూనాలు మరియు ఫ్రేమ్వర్క్లు
+
+దిగువన ఉన్న పట్టిక ఆ ప్రతి మోడల్కు పైథాన్ కలిగి ఉన్నా లైబ్రరీలో ప్రస్తుత మద్దతును సూచిస్తుంది
+టోకెనైజర్ ("నెమ్మదిగా" అని పిలుస్తారు). Jax (ద్వారా
+ఫ్లాక్స్), పైటార్చ్ మరియు/లేదా టెన్సర్ఫ్లో.
+
+
+
+| Model | PyTorch support | TensorFlow support | Flax Support |
+|:------------------------------------------------------------------------:|:---------------:|:------------------:|:------------:|
+| [ALBERT](model_doc/albert) | ✅ | ✅ | ✅ |
+| [ALIGN](model_doc/align) | ✅ | ❌ | ❌ |
+| [AltCLIP](model_doc/altclip) | ✅ | ❌ | ❌ |
+| [Audio Spectrogram Transformer](model_doc/audio-spectrogram-transformer) | ✅ | ❌ | ❌ |
+| [Autoformer](model_doc/autoformer) | ✅ | ❌ | ❌ |
+| [Bark](model_doc/bark) | ✅ | ❌ | ❌ |
+| [BART](model_doc/bart) | ✅ | ✅ | ✅ |
+| [BARThez](model_doc/barthez) | ✅ | ✅ | ✅ |
+| [BARTpho](model_doc/bartpho) | ✅ | ✅ | ✅ |
+| [BEiT](model_doc/beit) | ✅ | ❌ | ✅ |
+| [BERT](model_doc/bert) | ✅ | ✅ | ✅ |
+| [Bert Generation](model_doc/bert-generation) | ✅ | ❌ | ❌ |
+| [BertJapanese](model_doc/bert-japanese) | ✅ | ✅ | ✅ |
+| [BERTweet](model_doc/bertweet) | ✅ | ✅ | ✅ |
+| [BigBird](model_doc/big_bird) | ✅ | ❌ | ✅ |
+| [BigBird-Pegasus](model_doc/bigbird_pegasus) | ✅ | ❌ | ❌ |
+| [BioGpt](model_doc/biogpt) | ✅ | ❌ | ❌ |
+| [BiT](model_doc/bit) | ✅ | ❌ | ❌ |
+| [Blenderbot](model_doc/blenderbot) | ✅ | ✅ | ✅ |
+| [BlenderbotSmall](model_doc/blenderbot-small) | ✅ | ✅ | ✅ |
+| [BLIP](model_doc/blip) | ✅ | ✅ | ❌ |
+| [BLIP-2](model_doc/blip-2) | ✅ | ❌ | ❌ |
+| [BLOOM](model_doc/bloom) | ✅ | ❌ | ✅ |
+| [BORT](model_doc/bort) | ✅ | ✅ | ✅ |
+| [BridgeTower](model_doc/bridgetower) | ✅ | ❌ | ❌ |
+| [BROS](model_doc/bros) | ✅ | ❌ | ❌ |
+| [ByT5](model_doc/byt5) | ✅ | ✅ | ✅ |
+| [CamemBERT](model_doc/camembert) | ✅ | ✅ | ❌ |
+| [CANINE](model_doc/canine) | ✅ | ❌ | ❌ |
+| [Chinese-CLIP](model_doc/chinese_clip) | ✅ | ❌ | ❌ |
+| [CLAP](model_doc/clap) | ✅ | ❌ | ❌ |
+| [CLIP](model_doc/clip) | ✅ | ✅ | ✅ |
+| [CLIPSeg](model_doc/clipseg) | ✅ | ❌ | ❌ |
+| [CodeGen](model_doc/codegen) | ✅ | ❌ | ❌ |
+| [CodeLlama](model_doc/code_llama) | ✅ | ❌ | ❌ |
+| [Conditional DETR](model_doc/conditional_detr) | ✅ | ❌ | ❌ |
+| [ConvBERT](model_doc/convbert) | ✅ | ✅ | ❌ |
+| [ConvNeXT](model_doc/convnext) | ✅ | ✅ | ❌ |
+| [ConvNeXTV2](model_doc/convnextv2) | ✅ | ❌ | ❌ |
+| [CPM](model_doc/cpm) | ✅ | ✅ | ✅ |
+| [CPM-Ant](model_doc/cpmant) | ✅ | ❌ | ❌ |
+| [CTRL](model_doc/ctrl) | ✅ | ✅ | ❌ |
+| [CvT](model_doc/cvt) | ✅ | ✅ | ❌ |
+| [Data2VecAudio](model_doc/data2vec) | ✅ | ❌ | ❌ |
+| [Data2VecText](model_doc/data2vec) | ✅ | ❌ | ❌ |
+| [Data2VecVision](model_doc/data2vec) | ✅ | ✅ | ❌ |
+| [DeBERTa](model_doc/deberta) | ✅ | ✅ | ❌ |
+| [DeBERTa-v2](model_doc/deberta-v2) | ✅ | ✅ | ❌ |
+| [Decision Transformer](model_doc/decision_transformer) | ✅ | ❌ | ❌ |
+| [Deformable DETR](model_doc/deformable_detr) | ✅ | ❌ | ❌ |
+| [DeiT](model_doc/deit) | ✅ | ✅ | ❌ |
+| [DePlot](model_doc/deplot) | ✅ | ❌ | ❌ |
+| [DETA](model_doc/deta) | ✅ | ❌ | ❌ |
+| [DETR](model_doc/detr) | ✅ | ❌ | ❌ |
+| [DialoGPT](model_doc/dialogpt) | ✅ | ✅ | ✅ |
+| [DiNAT](model_doc/dinat) | ✅ | ❌ | ❌ |
+| [DINOv2](model_doc/dinov2) | ✅ | ❌ | ❌ |
+| [DistilBERT](model_doc/distilbert) | ✅ | ✅ | ✅ |
+| [DiT](model_doc/dit) | ✅ | ❌ | ✅ |
+| [DonutSwin](model_doc/donut) | ✅ | ❌ | ❌ |
+| [DPR](model_doc/dpr) | ✅ | ✅ | ❌ |
+| [DPT](model_doc/dpt) | ✅ | ❌ | ❌ |
+| [EfficientFormer](model_doc/efficientformer) | ✅ | ✅ | ❌ |
+| [EfficientNet](model_doc/efficientnet) | ✅ | ❌ | ❌ |
+| [ELECTRA](model_doc/electra) | ✅ | ✅ | ✅ |
+| [EnCodec](model_doc/encodec) | ✅ | ❌ | ❌ |
+| [Encoder decoder](model_doc/encoder-decoder) | ✅ | ✅ | ✅ |
+| [ERNIE](model_doc/ernie) | ✅ | ❌ | ❌ |
+| [ErnieM](model_doc/ernie_m) | ✅ | ❌ | ❌ |
+| [ESM](model_doc/esm) | ✅ | ✅ | ❌ |
+| [FairSeq Machine-Translation](model_doc/fsmt) | ✅ | ❌ | ❌ |
+| [Falcon](model_doc/falcon) | ✅ | ❌ | ❌ |
+| [FLAN-T5](model_doc/flan-t5) | ✅ | ✅ | ✅ |
+| [FLAN-UL2](model_doc/flan-ul2) | ✅ | ✅ | ✅ |
+| [FlauBERT](model_doc/flaubert) | ✅ | ✅ | ❌ |
+| [FLAVA](model_doc/flava) | ✅ | ❌ | ❌ |
+| [FNet](model_doc/fnet) | ✅ | ❌ | ❌ |
+| [FocalNet](model_doc/focalnet) | ✅ | ❌ | ❌ |
+| [Funnel Transformer](model_doc/funnel) | ✅ | ✅ | ❌ |
+| [GIT](model_doc/git) | ✅ | ❌ | ❌ |
+| [GLPN](model_doc/glpn) | ✅ | ❌ | ❌ |
+| [GPT Neo](model_doc/gpt_neo) | ✅ | ❌ | ✅ |
+| [GPT NeoX](model_doc/gpt_neox) | ✅ | ❌ | ❌ |
+| [GPT NeoX Japanese](model_doc/gpt_neox_japanese) | ✅ | ❌ | ❌ |
+| [GPT-J](model_doc/gptj) | ✅ | ✅ | ✅ |
+| [GPT-Sw3](model_doc/gpt-sw3) | ✅ | ✅ | ✅ |
+| [GPTBigCode](model_doc/gpt_bigcode) | ✅ | ❌ | ❌ |
+| [GPTSAN-japanese](model_doc/gptsan-japanese) | ✅ | ❌ | ❌ |
+| [Graphormer](model_doc/graphormer) | ✅ | ❌ | ❌ |
+| [GroupViT](model_doc/groupvit) | ✅ | ✅ | ❌ |
+| [HerBERT](model_doc/herbert) | ✅ | ✅ | ✅ |
+| [Hubert](model_doc/hubert) | ✅ | ✅ | ❌ |
+| [I-BERT](model_doc/ibert) | ✅ | ❌ | ❌ |
+| [IDEFICS](model_doc/idefics) | ✅ | ❌ | ❌ |
+| [ImageGPT](model_doc/imagegpt) | ✅ | ❌ | ❌ |
+| [Informer](model_doc/informer) | ✅ | ❌ | ❌ |
+| [InstructBLIP](model_doc/instructblip) | ✅ | ❌ | ❌ |
+| [Jukebox](model_doc/jukebox) | ✅ | ❌ | ❌ |
+| [LayoutLM](model_doc/layoutlm) | ✅ | ✅ | ❌ |
+| [LayoutLMv2](model_doc/layoutlmv2) | ✅ | ❌ | ❌ |
+| [LayoutLMv3](model_doc/layoutlmv3) | ✅ | ✅ | ❌ |
+| [LayoutXLM](model_doc/layoutxlm) | ✅ | ❌ | ❌ |
+| [LED](model_doc/led) | ✅ | ✅ | ❌ |
+| [LeViT](model_doc/levit) | ✅ | ❌ | ❌ |
+| [LiLT](model_doc/lilt) | ✅ | ❌ | ❌ |
+| [LLaMA](model_doc/llama) | ✅ | ❌ | ❌ |
+| [Llama2](model_doc/llama2) | ✅ | ❌ | ❌ |
+| [Longformer](model_doc/longformer) | ✅ | ✅ | ❌ |
+| [LongT5](model_doc/longt5) | ✅ | ❌ | ✅ |
+| [LUKE](model_doc/luke) | ✅ | ❌ | ❌ |
+| [LXMERT](model_doc/lxmert) | ✅ | ✅ | ❌ |
+| [M-CTC-T](model_doc/mctct) | ✅ | ❌ | ❌ |
+| [M2M100](model_doc/m2m_100) | ✅ | ❌ | ❌ |
+| [Marian](model_doc/marian) | ✅ | ✅ | ✅ |
+| [MarkupLM](model_doc/markuplm) | ✅ | ❌ | ❌ |
+| [Mask2Former](model_doc/mask2former) | ✅ | ❌ | ❌ |
+| [MaskFormer](model_doc/maskformer) | ✅ | ❌ | ❌ |
+| [MatCha](model_doc/matcha) | ✅ | ❌ | ❌ |
+| [mBART](model_doc/mbart) | ✅ | ✅ | ✅ |
+| [mBART-50](model_doc/mbart50) | ✅ | ✅ | ✅ |
+| [MEGA](model_doc/mega) | ✅ | ❌ | ❌ |
+| [Megatron-BERT](model_doc/megatron-bert) | ✅ | ❌ | ❌ |
+| [Megatron-GPT2](model_doc/megatron_gpt2) | ✅ | ✅ | ✅ |
+| [MGP-STR](model_doc/mgp-str) | ✅ | ❌ | ❌ |
+| [Mistral](model_doc/mistral) | ✅ | ❌ | ❌ |
+| [mLUKE](model_doc/mluke) | ✅ | ❌ | ❌ |
+| [MMS](model_doc/mms) | ✅ | ✅ | ✅ |
+| [MobileBERT](model_doc/mobilebert) | ✅ | ✅ | ❌ |
+| [MobileNetV1](model_doc/mobilenet_v1) | ✅ | ❌ | ❌ |
+| [MobileNetV2](model_doc/mobilenet_v2) | ✅ | ❌ | ❌ |
+| [MobileViT](model_doc/mobilevit) | ✅ | ✅ | ❌ |
+| [MobileViTV2](model_doc/mobilevitv2) | ✅ | ❌ | ❌ |
+| [MPNet](model_doc/mpnet) | ✅ | ✅ | ❌ |
+| [MPT](model_doc/mpt) | ✅ | ❌ | ❌ |
+| [MRA](model_doc/mra) | ✅ | ❌ | ❌ |
+| [MT5](model_doc/mt5) | ✅ | ✅ | ✅ |
+| [MusicGen](model_doc/musicgen) | ✅ | ❌ | ❌ |
+| [MVP](model_doc/mvp) | ✅ | ❌ | ❌ |
+| [NAT](model_doc/nat) | ✅ | ❌ | ❌ |
+| [Nezha](model_doc/nezha) | ✅ | ❌ | ❌ |
+| [NLLB](model_doc/nllb) | ✅ | ❌ | ❌ |
+| [NLLB-MOE](model_doc/nllb-moe) | ✅ | ❌ | ❌ |
+| [Nougat](model_doc/nougat) | ✅ | ✅ | ✅ |
+| [Nyströmformer](model_doc/nystromformer) | ✅ | ❌ | ❌ |
+| [OneFormer](model_doc/oneformer) | ✅ | ❌ | ❌ |
+| [OpenAI GPT](model_doc/openai-gpt) | ✅ | ✅ | ❌ |
+| [OpenAI GPT-2](model_doc/gpt2) | ✅ | ✅ | ✅ |
+| [OpenLlama](model_doc/open-llama) | ✅ | ❌ | ❌ |
+| [OPT](model_doc/opt) | ✅ | ✅ | ✅ |
+| [OWL-ViT](model_doc/owlvit) | ✅ | ❌ | ❌ |
+| [Pegasus](model_doc/pegasus) | ✅ | ✅ | ✅ |
+| [PEGASUS-X](model_doc/pegasus_x) | ✅ | ❌ | ❌ |
+| [Perceiver](model_doc/perceiver) | ✅ | ❌ | ❌ |
+| [Persimmon](model_doc/persimmon) | ✅ | ❌ | ❌ |
+| [PhoBERT](model_doc/phobert) | ✅ | ✅ | ✅ |
+| [Pix2Struct](model_doc/pix2struct) | ✅ | ❌ | ❌ |
+| [PLBart](model_doc/plbart) | ✅ | ❌ | ❌ |
+| [PoolFormer](model_doc/poolformer) | ✅ | ❌ | ❌ |
+| [Pop2Piano](model_doc/pop2piano) | ✅ | ❌ | ❌ |
+| [ProphetNet](model_doc/prophetnet) | ✅ | ❌ | ❌ |
+| [PVT](model_doc/pvt) | ✅ | ❌ | ❌ |
+| [QDQBert](model_doc/qdqbert) | ✅ | ❌ | ❌ |
+| [RAG](model_doc/rag) | ✅ | ✅ | ❌ |
+| [REALM](model_doc/realm) | ✅ | ❌ | ❌ |
+| [Reformer](model_doc/reformer) | ✅ | ❌ | ❌ |
+| [RegNet](model_doc/regnet) | ✅ | ✅ | ✅ |
+| [RemBERT](model_doc/rembert) | ✅ | ✅ | ❌ |
+| [ResNet](model_doc/resnet) | ✅ | ✅ | ✅ |
+| [RetriBERT](model_doc/retribert) | ✅ | ❌ | ❌ |
+| [RoBERTa](model_doc/roberta) | ✅ | ✅ | ✅ |
+| [RoBERTa-PreLayerNorm](model_doc/roberta-prelayernorm) | ✅ | ✅ | ✅ |
+| [RoCBert](model_doc/roc_bert) | ✅ | ❌ | ❌ |
+| [RoFormer](model_doc/roformer) | ✅ | ✅ | ✅ |
+| [RWKV](model_doc/rwkv) | ✅ | ❌ | ❌ |
+| [SAM](model_doc/sam) | ✅ | ✅ | ❌ |
+| [SegFormer](model_doc/segformer) | ✅ | ✅ | ❌ |
+| [SEW](model_doc/sew) | ✅ | ❌ | ❌ |
+| [SEW-D](model_doc/sew-d) | ✅ | ❌ | ❌ |
+| [Speech Encoder decoder](model_doc/speech-encoder-decoder) | ✅ | ❌ | ✅ |
+| [Speech2Text](model_doc/speech_to_text) | ✅ | ✅ | ❌ |
+| [SpeechT5](model_doc/speecht5) | ✅ | ❌ | ❌ |
+| [Splinter](model_doc/splinter) | ✅ | ❌ | ❌ |
+| [SqueezeBERT](model_doc/squeezebert) | ✅ | ❌ | ❌ |
+| [SwiftFormer](model_doc/swiftformer) | ✅ | ❌ | ❌ |
+| [Swin Transformer](model_doc/swin) | ✅ | ✅ | ❌ |
+| [Swin Transformer V2](model_doc/swinv2) | ✅ | ❌ | ❌ |
+| [Swin2SR](model_doc/swin2sr) | ✅ | ❌ | ❌ |
+| [SwitchTransformers](model_doc/switch_transformers) | ✅ | ❌ | ❌ |
+| [T5](model_doc/t5) | ✅ | ✅ | ✅ |
+| [T5v1.1](model_doc/t5v1.1) | ✅ | ✅ | ✅ |
+| [Table Transformer](model_doc/table-transformer) | ✅ | ❌ | ❌ |
+| [TAPAS](model_doc/tapas) | ✅ | ✅ | ❌ |
+| [TAPEX](model_doc/tapex) | ✅ | ✅ | ✅ |
+| [Time Series Transformer](model_doc/time_series_transformer) | ✅ | ❌ | ❌ |
+| [TimeSformer](model_doc/timesformer) | ✅ | ❌ | ❌ |
+| [Trajectory Transformer](model_doc/trajectory_transformer) | ✅ | ❌ | ❌ |
+| [Transformer-XL](model_doc/transfo-xl) | ✅ | ✅ | ❌ |
+| [TrOCR](model_doc/trocr) | ✅ | ❌ | ❌ |
+| [TVLT](model_doc/tvlt) | ✅ | ❌ | ❌ |
+| [UL2](model_doc/ul2) | ✅ | ✅ | ✅ |
+| [UMT5](model_doc/umt5) | ✅ | ❌ | ❌ |
+| [UniSpeech](model_doc/unispeech) | ✅ | ❌ | ❌ |
+| [UniSpeechSat](model_doc/unispeech-sat) | ✅ | ❌ | ❌ |
+| [UPerNet](model_doc/upernet) | ✅ | ❌ | ❌ |
+| [VAN](model_doc/van) | ✅ | ❌ | ❌ |
+| [VideoMAE](model_doc/videomae) | ✅ | ❌ | ❌ |
+| [ViLT](model_doc/vilt) | ✅ | ❌ | ❌ |
+| [Vision Encoder decoder](model_doc/vision-encoder-decoder) | ✅ | ✅ | ✅ |
+| [VisionTextDualEncoder](model_doc/vision-text-dual-encoder) | ✅ | ✅ | ✅ |
+| [VisualBERT](model_doc/visual_bert) | ✅ | ❌ | ❌ |
+| [ViT](model_doc/vit) | ✅ | ✅ | ✅ |
+| [ViT Hybrid](model_doc/vit_hybrid) | ✅ | ❌ | ❌ |
+| [VitDet](model_doc/vitdet) | ✅ | ❌ | ❌ |
+| [ViTMAE](model_doc/vit_mae) | ✅ | ✅ | ❌ |
+| [ViTMatte](model_doc/vitmatte) | ✅ | ❌ | ❌ |
+| [ViTMSN](model_doc/vit_msn) | ✅ | ❌ | ❌ |
+| [VITS](model_doc/vits) | ✅ | ❌ | ❌ |
+| [ViViT](model_doc/vivit) | ✅ | ❌ | ❌ |
+| [Wav2Vec2](model_doc/wav2vec2) | ✅ | ✅ | ✅ |
+| [Wav2Vec2-Conformer](model_doc/wav2vec2-conformer) | ✅ | ❌ | ❌ |
+| [Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme) | ✅ | ✅ | ✅ |
+| [WavLM](model_doc/wavlm) | ✅ | ❌ | ❌ |
+| [Whisper](model_doc/whisper) | ✅ | ✅ | ✅ |
+| [X-CLIP](model_doc/xclip) | ✅ | ❌ | ❌ |
+| [X-MOD](model_doc/xmod) | ✅ | ❌ | ❌ |
+| [XGLM](model_doc/xglm) | ✅ | ✅ | ✅ |
+| [XLM](model_doc/xlm) | ✅ | ✅ | ❌ |
+| [XLM-ProphetNet](model_doc/xlm-prophetnet) | ✅ | ❌ | ❌ |
+| [XLM-RoBERTa](model_doc/xlm-roberta) | ✅ | ✅ | ✅ |
+| [XLM-RoBERTa-XL](model_doc/xlm-roberta-xl) | ✅ | ❌ | ❌ |
+| [XLM-V](model_doc/xlm-v) | ✅ | ✅ | ✅ |
+| [XLNet](model_doc/xlnet) | ✅ | ✅ | ❌ |
+| [XLS-R](model_doc/xls_r) | ✅ | ✅ | ✅ |
+| [XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2) | ✅ | ✅ | ✅ |
+| [YOLOS](model_doc/yolos) | ✅ | ❌ | ❌ |
+| [YOSO](model_doc/yoso) | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/te/quicktour.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/te/quicktour.md
new file mode 100644
index 0000000000000000000000000000000000000000..6045b673d2d3d0e71f097ff6666f3dd9bb9a5f06
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/te/quicktour.md
@@ -0,0 +1,557 @@
+
+
+# శీఘ్ర పర్యటన
+
+[[ఓపెన్-ఇన్-కోలాబ్]]
+
+🤗 ట్రాన్స్ఫార్మర్లతో లేచి పరుగెత్తండి! మీరు డెవలపర్ అయినా లేదా రోజువారీ వినియోగదారు అయినా, ఈ శీఘ్ర పర్యటన మీకు ప్రారంభించడానికి సహాయం చేస్తుంది మరియు [`pipeline`] అనుమితి కోసం ఎలా ఉపయోగించాలో మీకు చూపుతుంది, [AutoClass](./model_doc/auto) తో ప్రీట్రైన్డ్ మోడల్ మరియు ప్రిప్రాసెసర్/ ఆటో, మరియు PyTorch లేదా TensorFlowతో మోడల్కు త్వరగా శిక్షణ ఇవ్వండి. మీరు ఒక అనుభవశూన్యుడు అయితే, ఇక్కడ పరిచయం చేయబడిన భావనల గురించి మరింత లోతైన వివరణల కోసం మా ట్యుటోరియల్స్ లేదా [course](https://huggingface.co/course/chapter1/1)ని తనిఖీ చేయమని మేము సిఫార్సు చేస్తున్నాము.
+
+మీరు ప్రారంభించడానికి ముందు, మీరు అవసరమైన అన్ని లైబ్రరీలను ఇన్స్టాల్ చేశారని నిర్ధారించుకోండి:
+
+```bash
+!pip install transformers datasets evaluate accelerate
+```
+
+మీరు మీ ప్రాధాన్య యంత్ర అభ్యాస ఫ్రేమ్వర్క్ను కూడా ఇన్స్టాల్ చేయాలి:
+
+
+
+
+```bash
+pip install torch
+```
+
+
+
+```bash
+pip install tensorflow
+```
+
+
+
+## పైప్లైన్
+
+
+
+అందుబాటులో ఉన్న పనుల పూర్తి జాబితా కోసం, [పైప్లైన్ API సూచన](./main_classes/pipelines)ని తనిఖీ చేయండి.
+
+
+
+Here is the translation in Telugu:
+
+| **పని** | **వివరణ** | **మోడాలిటీ** | **పైప్లైన్ ఐడెంటిఫైయర్** |
+|------------------------------|--------------------------------------------------------------------------------------------------------|-----------------|------------------------------------------|
+| వచన వర్గీకరణు | కొన్ని వచనాల అంతా ఒక లేబుల్ను కొడి | NLP | pipeline(task=“sentiment-analysis”) |
+| వచన సృష్టి | ప్రమ్పుటం కలిగినంత వచనం సృష్టించండి | NLP | pipeline(task=“text-generation”) |
+| సంక్షేపణ | వచనం లేదా పత్రం కొరకు సంక్షేపణ తయారుచేసండి | NLP | pipeline(task=“summarization”) |
+| చిత్రం వర్గీకరణు | చిత్రంలో ఒక లేబుల్ను కొడి | కంప్యూటర్ విషయం | pipeline(task=“image-classification”) |
+| చిత్రం విభజన | ఒక చిత్రంలో ప్రతి వ్యక్తిగత పిక్సల్ను ఒక లేబుల్గా నమోదు చేయండి (సెమాంటిక్, పానొప్టిక్, మరియు ఇన్స్టన్స్ విభజనలను మద్దతు చేస్తుంది) | కంప్యూటర్ విషయం | pipeline(task=“image-segmentation”) |
+| వస్త్రం గుర్తువు | ఒక చిత్రంలో పదాల యొక్క బౌండింగ్ బాక్స్లను మరియు వస్త్రాల వర్గాలను అంచనా చేయండి | కంప్యూటర్ విషయం | pipeline(task=“object-detection”) |
+| ఆడియో గుర్తువు | కొన్ని ఆడియో డేటానికి ఒక లేబుల్ను కొడి | ఆడియో | pipeline(task=“audio-classification”) |
+| స్వయంచలన ప్రసంగ గుర్తువు | ప్రసంగాన్ని వచనంగా వర్ణించండి | ఆడియో | pipeline(task=“automatic-speech-recognition”) |
+| దృశ్య ప్రశ్న సంవాదం | వచనం మరియు ప్రశ్నను నమోదు చేసిన చిత్రంతో ప్రశ్నకు సమాధానం ఇవ్వండి | బహుమూలిక | pipeline(task=“vqa”) |
+| పత్రం ప్రశ్న సంవాదం | ప్రశ్నను పత్రం లేదా డాక్యుమెంట్తో సమాధానం ఇవ్వండి | బహుమూలిక | pipeline(task="document-question-answering") |
+| చిత్రం వ్రాసాయింగ్ | కొన్ని చిత్రానికి పిటియార్లను సృష్టించండి | బహుమూలిక | pipeline(task="image-to-text") |
+
+
+[`pipeline`] యొక్క ఉదాహరణను సృష్టించడం ద్వారా మరియు మీరు దానిని ఉపయోగించాలనుకుంటున్న పనిని పేర్కొనడం ద్వారా ప్రారంభించండి. ఈ గైడ్లో, మీరు సెంటిమెంట్ విశ్లేషణ కోసం [`pipeline`]ని ఉదాహరణగా ఉపయోగిస్తారు:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("sentiment-analysis")
+```
+
+సెంటిమెంట్ విశ్లేషణ కోసం [`pipeline`] డిఫాల్ట్ [ప్రీట్రైన్డ్ మోడల్](https://huggingface.co/distilbert/distilbert-base-uncased-finetuned-sst-2-english) మరియు టోకెనైజర్ని డౌన్లోడ్ చేస్తుంది మరియు కాష్ చేస్తుంది. ఇప్పుడు మీరు మీ లక్ష్య వచనంలో `classifier`ని ఉపయోగించవచ్చు:
+
+```py
+>>> classifier("We are very happy to show you the 🤗 Transformers library.")
+[{'label': 'POSITIVE', 'score': 0.9998}]
+```
+
+మీరు ఒకటి కంటే ఎక్కువ ఇన్పుట్లను కలిగి ఉంటే, నిఘంటువుల జాబితాను అందించడానికి మీ ఇన్పుట్లను జాబితాగా [`pipeline`]కి పంపండి:
+
+```py
+>>> results = classifier(["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."])
+>>> for result in results:
+... print(f"label: {result['label']}, with score: {round(result['score'], 4)}")
+label: POSITIVE, with score: 0.9998
+label: NEGATIVE, with score: 0.5309
+```
+
+[`pipeline`] మీకు నచ్చిన ఏదైనా పని కోసం మొత్తం డేటాసెట్ను కూడా పునరావృతం చేయగలదు. ఈ ఉదాహరణ కోసం, స్వయంచాలక ప్రసంగ గుర్తింపును మన పనిగా ఎంచుకుందాం:
+
+```py
+>>> import torch
+>>> from transformers import pipeline
+
+>>> speech_recognizer = pipeline("automatic-speech-recognition", model="facebook/wav2vec2-base-960h")
+```
+
+మీరు మళ్లీ మళ్లీ చెప్పాలనుకుంటున్న ఆడియో డేటాసెట్ను లోడ్ చేయండి (మరిన్ని వివరాల కోసం 🤗 డేటాసెట్లు [త్వరిత ప్రారంభం](https://huggingface.co/docs/datasets/quickstart#audio) చూడండి. ఉదాహరణకు, [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) డేటాసెట్ను లోడ్ చేయండి:
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train") # doctest: +IGNORE_RESULT
+```
+
+డేటాసెట్ యొక్క నమూనా రేటు నమూనాతో సరిపోలుతుందని మీరు నిర్ధారించుకోవాలి
+రేటు [`facebook/wav2vec2-base-960h`](https://huggingface.co/facebook/wav2vec2-base-960h) దీనిపై శిక్షణ పొందింది:
+
+```py
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=speech_recognizer.feature_extractor.sampling_rate))
+```
+
+`"ఆడియో"` కాలమ్కి కాల్ చేస్తున్నప్పుడు ఆడియో ఫైల్లు స్వయంచాలకంగా లోడ్ చేయబడతాయి మరియు మళ్లీ నమూనా చేయబడతాయి.
+మొదటి 4 నమూనాల నుండి ముడి వేవ్ఫార్మ్ శ్రేణులను సంగ్రహించి, పైప్లైన్కు జాబితాగా పాస్ చేయండి:
+
+```py
+>>> result = speech_recognizer(dataset[:4]["audio"])
+>>> print([d["text"] for d in result])
+['I WOULD LIKE TO SET UP A JOINT ACCOUNT WITH MY PARTNER HOW DO I PROCEED WITH DOING THAT', "FONDERING HOW I'D SET UP A JOIN TO HELL T WITH MY WIFE AND WHERE THE AP MIGHT BE", "I I'D LIKE TOY SET UP A JOINT ACCOUNT WITH MY PARTNER I'M NOT SEEING THE OPTION TO DO IT ON THE APSO I CALLED IN TO GET SOME HELP CAN I JUST DO IT OVER THE PHONE WITH YOU AND GIVE YOU THE INFORMATION OR SHOULD I DO IT IN THE AP AN I'M MISSING SOMETHING UQUETTE HAD PREFERRED TO JUST DO IT OVER THE PHONE OF POSSIBLE THINGS", 'HOW DO I FURN A JOINA COUT']
+```
+
+ఇన్పుట్లు పెద్దగా ఉన్న పెద్ద డేటాసెట్ల కోసం (స్పీచ్ లేదా విజన్ వంటివి), మెమరీలోని అన్ని ఇన్పుట్లను లోడ్ చేయడానికి మీరు జాబితాకు బదులుగా జెనరేటర్ను పాస్ చేయాలనుకుంటున్నారు. మరింత సమాచారం కోసం [పైప్లైన్ API సూచన](./main_classes/pipelines)ని చూడండి.
+
+### పైప్లైన్లో మరొక మోడల్ మరియు టోకెనైజర్ని ఉపయోగించండి
+
+[`pipeline`] [Hub](https://huggingface.co/models) నుండి ఏదైనా మోడల్ను కలిగి ఉంటుంది, దీని వలన ఇతర వినియోగ-కేసుల కోసం [`pipeline`]ని సులభంగా స్వీకరించవచ్చు. ఉదాహరణకు, మీరు ఫ్రెంచ్ టెక్స్ట్ను హ్యాండిల్ చేయగల మోడల్ కావాలనుకుంటే, తగిన మోడల్ కోసం ఫిల్టర్ చేయడానికి హబ్లోని ట్యాగ్లను ఉపయోగించండి. అగ్ర ఫిల్టర్ చేసిన ఫలితం మీరు ఫ్రెంచ్ టెక్స్ట్ కోసం ఉపయోగించగల సెంటిమెంట్ విశ్లేషణ కోసం ఫైన్ట్యూన్ చేయబడిన బహుభాషా [BERT మోడల్](https://huggingface.co/nlptown/bert-base-multilingual-uncased-sentiment)ని అందిస్తుంది:
+
+```py
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+```
+
+
+
+ముందుగా శిక్షణ పొందిన మోడల్ను లోడ్ చేయడానికి [`AutoModelForSequenceClassification`] మరియు [`AutoTokenizer`]ని ఉపయోగించండి మరియు దాని అనుబంధిత టోకెనైజర్ (తదుపరి విభాగంలో `AutoClass`పై మరిన్ని):
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+ముందుగా శిక్షణ పొందిన మోడల్ను లోడ్ చేయడానికి [`TFAutoModelForSequenceClassification`] మరియు [`AutoTokenizer`]ని ఉపయోగించండి మరియు దాని అనుబంధిత టోకెనైజర్ (తదుపరి విభాగంలో `TFAutoClass`పై మరిన్ని):
+
+```py
+>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+
+[`pipeline`]లో మోడల్ మరియు టోకెనైజర్ను పేర్కొనండి మరియు ఇప్పుడు మీరు ఫ్రెంచ్ టెక్స్ట్పై `క్లాసిఫైయర్`ని వర్తింపజేయవచ్చు:
+
+```py
+>>> classifier = pipeline("sentiment-analysis", model=model, tokenizer=tokenizer)
+>>> classifier("Nous sommes très heureux de vous présenter la bibliothèque 🤗 Transformers.")
+[{'label': '5 stars', 'score': 0.7273}]
+```
+
+మీరు మీ వినియోగ-కేస్ కోసం మోడల్ను కనుగొనలేకపోతే, మీరు మీ డేటాపై ముందుగా శిక్షణ పొందిన మోడల్ను చక్కగా మార్చాలి. ఎలాగో తెలుసుకోవడానికి మా [ఫైన్ట్యూనింగ్ ట్యుటోరియల్](./training)ని చూడండి. చివరగా, మీరు మీ ప్రీట్రైన్డ్ మోడల్ని ఫైన్ట్యూన్ చేసిన తర్వాత, దయచేసి అందరి కోసం మెషిన్ లెర్నింగ్ని డెమోక్రటైజ్ చేయడానికి హబ్లోని సంఘంతో మోడల్ను [షేరింగ్](./model_sharing) పరిగణించండి! 🤗
+
+## AutoClass
+
+
+
+
+```py
+>>> pt_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="pt",
+... )
+```
+
+
+
+```py
+>>> tf_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="tf",
+... )
+```
+
+
+
+
+
+టోకనైజేషన్ గురించి మరిన్ని వివరాల కోసం [ప్రీప్రాసెస్](./preprocessing) ట్యుటోరియల్ని చూడండి మరియు ఇమేజ్, ఆడియో మరియు మల్టీమోడల్ ఇన్పుట్లను ప్రీప్రాసెస్ చేయడానికి [`AutoImageProcessor`], [`AutoFeatureExtractor`] మరియు [`AutoProcessor`] ఎలా ఉపయోగించాలి.
+
+
+
+### AutoModel
+
+
+
+🤗 ట్రాన్స్ఫార్మర్లు ప్రీట్రైన్డ్ ఇన్స్టాన్స్లను లోడ్ చేయడానికి సులభమైన మరియు ఏకీకృత మార్గాన్ని అందిస్తాయి. దీని అర్థం మీరు [`AutoTokenizer`]ని లోడ్ చేసినట్లుగా [`AutoModel`]ని లోడ్ చేయవచ్చు. టాస్క్ కోసం సరైన [`AutoModel`]ని ఎంచుకోవడం మాత్రమే తేడా. టెక్స్ట్ (లేదా సీక్వెన్స్) వర్గీకరణ కోసం, మీరు [`AutoModelForSequenceClassification`]ని లోడ్ చేయాలి:
+
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+[`AutoModel`] క్లాస్ ద్వారా సపోర్ట్ చేసే టాస్క్ల కోసం [టాస్క్ సారాంశం](./task_summary)ని చూడండి.
+
+
+
+ఇప్పుడు మీ ప్రీప్రాసెస్ చేయబడిన బ్యాచ్ ఇన్పుట్లను నేరుగా మోడల్కి పంపండి. మీరు `**`ని జోడించడం ద్వారా నిఘంటువుని అన్ప్యాక్ చేయాలి:
+
+```py
+>>> pt_outputs = pt_model(**pt_batch)
+```
+
+మోడల్ తుది యాక్టివేషన్లను `logits` లక్షణంలో అవుట్పుట్ చేస్తుంది. సంభావ్యతలను తిరిగి పొందడానికి సాఫ్ట్మాక్స్ ఫంక్షన్ను `logits` కు వర్తింపజేయండి:
+
+
+```py
+>>> from torch import nn
+
+>>> pt_predictions = nn.functional.softmax(pt_outputs.logits, dim=-1)
+>>> print(pt_predictions)
+tensor([[0.0021, 0.0018, 0.0115, 0.2121, 0.7725],
+ [0.2084, 0.1826, 0.1969, 0.1755, 0.2365]], grad_fn=)
+```
+
+
+
+🤗 ట్రాన్స్ఫార్మర్లు ప్రీట్రైన్డ్ ఇన్స్టాన్స్లను లోడ్ చేయడానికి సులభమైన మరియు ఏకీకృత మార్గాన్ని అందిస్తాయి. మీరు [`AutoTokenizer`]ని లోడ్ చేసినట్లుగా మీరు [`TFAutoModel`]ని లోడ్ చేయవచ్చని దీని అర్థం. టాస్క్ కోసం సరైన [`TFAutoModel`]ని ఎంచుకోవడం మాత్రమే తేడా. టెక్స్ట్ (లేదా సీక్వెన్స్) వర్గీకరణ కోసం, మీరు [`TFAutoModelForSequenceClassification`]ని లోడ్ చేయాలి:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+[`AutoModel`] క్లాస్ ద్వారా సపోర్ట్ చేసే టాస్క్ల కోసం [టాస్క్ సారాంశం](./task_summary)ని చూడండి.
+
+
+
+ఇప్పుడు మీ ప్రీప్రాసెస్ చేయబడిన బ్యాచ్ ఇన్పుట్లను నేరుగా మోడల్కి పంపండి. మీరు టెన్సర్లను ఇలా పాస్ చేయవచ్చు:
+
+```py
+>>> tf_outputs = tf_model(tf_batch)
+```
+
+మోడల్ తుది యాక్టివేషన్లను `logits` లక్షణంలో అవుట్పుట్ చేస్తుంది. సంభావ్యతలను తిరిగి పొందడానికి సాఫ్ట్మాక్స్ ఫంక్షన్ను `logits`కు వర్తింపజేయండి:
+
+```py
+>>> import tensorflow as tf
+
+>>> tf_predictions = tf.nn.softmax(tf_outputs.logits, axis=-1)
+>>> tf_predictions # doctest: +IGNORE_RESULT
+```
+
+
+
+
+
+అన్ని 🤗 ట్రాన్స్ఫార్మర్స్ మోడల్లు (PyTorch లేదా TensorFlow) తుది యాక్టివేషన్కు *ముందు* టెన్సర్లను అవుట్పుట్ చేస్తాయి
+ఫంక్షన్ (softmax వంటిది) ఎందుకంటే చివరి యాక్టివేషన్ ఫంక్షన్ తరచుగా నష్టంతో కలిసిపోతుంది. మోడల్ అవుట్పుట్లు ప్రత్యేక డేటాక్లాస్లు కాబట్టి వాటి లక్షణాలు IDEలో స్వయంచాలకంగా పూర్తి చేయబడతాయి. మోడల్ అవుట్పుట్లు టుపుల్ లేదా డిక్షనరీ లాగా ప్రవర్తిస్తాయి (మీరు పూర్ణాంకం, స్లైస్ లేదా స్ట్రింగ్తో ఇండెక్స్ చేయవచ్చు) ఈ సందర్భంలో, ఏదీ లేని గుణాలు విస్మరించబడతాయి.
+
+
+
+### మోడల్ను సేవ్ చేయండి
+
+
+
+మీ మోడల్ చక్కగా ట్యూన్ చేయబడిన తర్వాత, మీరు దానిని [`PreTrainedModel.save_pretrained`]ని ఉపయోగించి దాని టోకెనైజర్తో సేవ్ చేయవచ్చు:
+
+```py
+>>> pt_save_directory = "./pt_save_pretrained"
+>>> tokenizer.save_pretrained(pt_save_directory) # doctest: +IGNORE_RESULT
+>>> pt_model.save_pretrained(pt_save_directory)
+```
+
+మీరు మోడల్ని మళ్లీ ఉపయోగించడానికి సిద్ధంగా ఉన్నప్పుడు, దాన్ని [`PreTrainedModel.from_pretrained`]తో రీలోడ్ చేయండి:
+
+```py
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained("./pt_save_pretrained")
+```
+
+
+మీ మోడల్ చక్కగా ట్యూన్ చేయబడిన తర్వాత, మీరు దానిని [`TFPreTrainedModel.save_pretrained`]ని ఉపయోగించి దాని టోకెనైజర్తో సేవ్ చేయవచ్చు:
+
+```py
+>>> tf_save_directory = "./tf_save_pretrained"
+>>> tokenizer.save_pretrained(tf_save_directory) # doctest: +IGNORE_RESULT
+>>> tf_model.save_pretrained(tf_save_directory)
+```
+మీరు మోడల్ని మళ్లీ ఉపయోగించడానికి సిద్ధంగా ఉన్నప్పుడు, దాన్ని [`TFPreTrainedModel.from_pretrained`]తో రీలోడ్ చేయండి:
+
+```py
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("./tf_save_pretrained")
+```
+
+
+
+ఒక ప్రత్యేకించి అద్భుతమైన 🤗 ట్రాన్స్ఫార్మర్స్ ఫీచర్ మోడల్ను సేవ్ చేయగల సామర్థ్యం మరియు దానిని PyTorch లేదా TensorFlow మోడల్గా రీలోడ్ చేయగలదు. `from_pt` లేదా `from_tf` పరామితి మోడల్ను ఒక ఫ్రేమ్వర్క్ నుండి మరొక ఫ్రేమ్వర్క్కి మార్చగలదు:
+
+
+
+
+```py
+>>> from transformers import AutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(pt_save_directory)
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(pt_save_directory, from_pt=True)
+```
+
+
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(tf_save_directory)
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(tf_save_directory, from_tf=True)
+```
+
+
+
+## కస్టమ్ మోడల్ బిల్డ్స్
+మోడల్ ఎలా నిర్మించబడుతుందో మార్చడానికి మీరు మోడల్ కాన్ఫిగరేషన్ క్లాస్ని సవరించవచ్చు. దాచిన లేయర్లు లేదా అటెన్షన్ హెడ్ల సంఖ్య వంటి మోడల్ లక్షణాలను కాన్ఫిగరేషన్ నిర్దేశిస్తుంది. మీరు కస్టమ్ కాన్ఫిగరేషన్ క్లాస్ నుండి మోడల్ను ప్రారంభించినప్పుడు మీరు మొదటి నుండి ప్రారంభిస్తారు. మోడల్ అట్రిబ్యూట్లు యాదృచ్ఛికంగా ప్రారంభించబడ్డాయి మరియు అర్థవంతమైన ఫలితాలను పొందడానికి మీరు మోడల్ను ఉపయోగించే ముందు దానికి శిక్షణ ఇవ్వాలి.
+
+[`AutoConfig`]ని దిగుమతి చేయడం ద్వారా ప్రారంభించండి, ఆపై మీరు సవరించాలనుకుంటున్న ప్రీట్రైన్డ్ మోడల్ను లోడ్ చేయండి. [`AutoConfig.from_pretrained`]లో, మీరు అటెన్షన్ హెడ్ల సంఖ్య వంటి మీరు మార్చాలనుకుంటున్న లక్షణాన్ని పేర్కొనవచ్చు:
+
+```py
+>>> from transformers import AutoConfig
+
+>>> my_config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased", n_heads=12)
+```
+
+
+
+[`AutoModel.from_config`]తో మీ అనుకూల కాన్ఫిగరేషన్ నుండి మోడల్ను సృష్టించండి:
+
+```py
+>>> from transformers import AutoModel
+
+>>> my_model = AutoModel.from_config(my_config)
+```
+
+
+[`TFAutoModel.from_config`]తో మీ అనుకూల కాన్ఫిగరేషన్ నుండి మోడల్ను సృష్టించండి:
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> my_model = TFAutoModel.from_config(my_config)
+```
+
+
+
+అనుకూల కాన్ఫిగరేషన్లను రూపొందించడం గురించి మరింత సమాచారం కోసం [కస్టమ్ ఆర్కిటెక్చర్ని సృష్టించండి](./create_a_model) గైడ్ను చూడండి.
+
+## శిక్షకుడు - పైటార్చ్ ఆప్టిమైజ్ చేసిన శిక్షణ లూప్
+
+అన్ని మోడల్లు ప్రామాణికమైన [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) కాబట్టి మీరు వాటిని ఏదైనా సాధారణ శిక్షణ లూప్లో ఉపయోగించవచ్చు. మీరు మీ స్వంత శిక్షణ లూప్ను వ్రాయగలిగినప్పటికీ, 🤗 ట్రాన్స్ఫార్మర్లు PyTorch కోసం [`ట్రైనర్`] తరగతిని అందజేస్తాయి, ఇందులో ప్రాథమిక శిక్షణ లూప్ ఉంటుంది మరియు పంపిణీ చేయబడిన శిక్షణ, మిశ్రమ ఖచ్చితత్వం మరియు మరిన్ని వంటి ఫీచర్ల కోసం అదనపు కార్యాచరణను జోడిస్తుంది.
+
+మీ విధిని బట్టి, మీరు సాధారణంగా కింది పారామితులను [`ట్రైనర్`]కి పంపుతారు:
+
+1. మీరు [`PreTrainedModel`] లేదా [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module)తో ప్రారంభిస్తారు:
+ ```py
+ >>> from transformers import AutoModelForSequenceClassification
+
+ >>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+2. [`TrainingArguments`] మీరు నేర్చుకునే రేటు, బ్యాచ్ పరిమాణం మరియు శిక్షణ పొందవలసిన యుగాల సంఖ్య వంటి మార్చగల మోడల్ హైపర్పారామీటర్లను కలిగి ఉంది. మీరు ఎలాంటి శిక్షణా వాదనలను పేర్కొనకుంటే డిఫాల్ట్ విలువలు ఉపయోగించబడతాయి:
+
+ ```py
+ >>> from transformers import TrainingArguments
+
+ >>> training_args = TrainingArguments(
+ ... output_dir="path/to/save/folder/",
+ ... learning_rate=2e-5,
+ ... per_device_train_batch_size=8,
+ ... per_device_eval_batch_size=8,
+ ... num_train_epochs=2,
+ ... )
+ ```
+
+3. టోకెనైజర్, ఇమేజ్ ప్రాసెసర్, ఫీచర్ ఎక్స్ట్రాక్టర్ లేదా ప్రాసెసర్ వంటి ప్రీప్రాసెసింగ్ క్లాస్ని లోడ్ చేయండి:
+ ```py
+ >>> from transformers import AutoTokenizer
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+4. డేటాసెట్ను లోడ్ చేయండి:
+
+ ```py
+ >>> from datasets import load_dataset
+
+ >>> dataset = load_dataset("rotten_tomatoes") # doctest: +IGNORE_RESULT
+ ```
+
+5. డేటాసెట్ను టోకనైజ్ చేయడానికి ఒక ఫంక్షన్ను సృష్టించండి:
+
+ ```py
+ >>> def tokenize_dataset(dataset):
+ ... return tokenizer(dataset["text"])
+ ```
+
+ ఆపై దానిని [`~datasets.Dataset.map`]తో మొత్తం డేటాసెట్లో వర్తింపజేయండి:
+
+ ```py
+ >>> dataset = dataset.map(tokenize_dataset, batched=True)
+ ```
+
+6. మీ డేటాసెట్ నుండి ఉదాహరణల సమూహాన్ని సృష్టించడానికి [`DataCollatorWithPadding`]:
+
+ ```py
+ >>> from transformers import DataCollatorWithPadding
+
+ >>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
+ ```
+
+ఇప్పుడు ఈ తరగతులన్నింటినీ [`Trainer`]లో సేకరించండి:
+
+```py
+>>> from transformers import Trainer
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=dataset["train"],
+... eval_dataset=dataset["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... ) # doctest: +SKIP
+```
+
+మీరు సిద్ధంగా ఉన్నప్పుడు, శిక్షణను ప్రారంభించడానికి [`~Trainer.train`]కి కాల్ చేయండి:
+
+```py
+>>> trainer.train() # doctest: +SKIP
+```
+
+
+
+సీక్వెన్స్-టు-సీక్వెన్స్ మోడల్ని ఉపయోగించే - అనువాదం లేదా సారాంశం వంటి పనుల కోసం, బదులుగా [`Seq2SeqTrainer`] మరియు [`Seq2SeqTrainingArguments`] తరగతులను ఉపయోగించండి.
+
+
+
+మీరు [`Trainer`] లోపల ఉన్న పద్ధతులను ఉపవర్గీకరించడం ద్వారా శిక్షణ లూప్ ప్రవర్తనను అనుకూలీకరించవచ్చు. ఇది లాస్ ఫంక్షన్, ఆప్టిమైజర్ మరియు షెడ్యూలర్ వంటి లక్షణాలను అనుకూలీకరించడానికి మిమ్మల్ని అనుమతిస్తుంది. ఉపవర్గీకరించబడే పద్ధతుల కోసం [`Trainer`] సూచనను పరిశీలించండి.
+
+శిక్షణ లూప్ను అనుకూలీకరించడానికి మరొక మార్గం [కాల్బ్యాక్లు](./main_classes/callback). మీరు ఇతర లైబ్రరీలతో అనుసంధానం చేయడానికి కాల్బ్యాక్లను ఉపయోగించవచ్చు మరియు పురోగతిపై నివేదించడానికి శిక్షణ లూప్ను తనిఖీ చేయవచ్చు లేదా శిక్షణను ముందుగానే ఆపవచ్చు. శిక్షణ లూప్లోనే కాల్బ్యాక్లు దేనినీ సవరించవు. లాస్ ఫంక్షన్ వంటివాటిని అనుకూలీకరించడానికి, మీరు బదులుగా [`Trainer`]ని ఉపవర్గం చేయాలి.
+
+## TensorFlowతో శిక్షణ పొందండి
+
+అన్ని మోడల్లు ప్రామాణికమైన [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) కాబట్టి వాటిని [Keras]తో TensorFlowలో శిక్షణ పొందవచ్చు(https: //keras.io/) API. 🤗 ట్రాన్స్ఫార్మర్లు మీ డేటాసెట్ని సులభంగా `tf.data.Dataset`గా లోడ్ చేయడానికి [`~TFPreTrainedModel.prepare_tf_dataset`] పద్ధతిని అందజేస్తుంది కాబట్టి మీరు వెంటనే Keras' [`compile`](https://keras.io/api/models/model_training_apis/#compile-method) మరియు [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) పద్ధతులు.
+
+1. మీరు [`TFPreTrainedModel`] లేదా [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model)తో ప్రారంభిస్తారు:
+ ```py
+ >>> from transformers import TFAutoModelForSequenceClassification
+
+ >>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+2. టోకెనైజర్, ఇమేజ్ ప్రాసెసర్, ఫీచర్ ఎక్స్ట్రాక్టర్ లేదా ప్రాసెసర్ వంటి ప్రీప్రాసెసింగ్ క్లాస్ని లోడ్ చేయండి:
+
+ ```py
+ >>> from transformers import AutoTokenizer
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+3. డేటాసెట్ను టోకనైజ్ చేయడానికి ఒక ఫంక్షన్ను సృష్టించండి:
+
+ ```py
+ >>> def tokenize_dataset(dataset):
+ ... return tokenizer(dataset["text"]) # doctest: +SKIP
+ ```
+
+4. [`~datasets.Dataset.map`]తో మొత్తం డేటాసెట్పై టోకెనైజర్ని వర్తింపజేయి, ఆపై డేటాసెట్ మరియు టోకెనైజర్ను [`~TFPreTrainedModel.prepare_tf_dataset`]కి పంపండి. మీరు కావాలనుకుంటే బ్యాచ్ పరిమాణాన్ని కూడా మార్చవచ్చు మరియు డేటాసెట్ను ఇక్కడ షఫుల్ చేయవచ్చు:
+ ```py
+ >>> dataset = dataset.map(tokenize_dataset) # doctest: +SKIP
+ >>> tf_dataset = model.prepare_tf_dataset(
+ ... dataset["train"], batch_size=16, shuffle=True, tokenizer=tokenizer
+ ... ) # doctest: +SKIP
+ ```
+
+5. మీరు సిద్ధంగా ఉన్నప్పుడు, శిక్షణను ప్రారంభించడానికి మీరు `కంపైల్` మరియు `ఫిట్`కి కాల్ చేయవచ్చు. ట్రాన్స్ఫార్మర్స్ మోడల్స్ అన్నీ డిఫాల్ట్ టాస్క్-సంబంధిత లాస్ ఫంక్షన్ని కలిగి ఉన్నాయని గుర్తుంచుకోండి, కాబట్టి మీరు కోరుకునే వరకు మీరు ఒకదానిని పేర్కొనవలసిన అవసరం లేదు:
+
+ ```py
+ >>> from tensorflow.keras.optimizers import Adam
+
+ >>> model.compile(optimizer=Adam(3e-5)) # No loss argument!
+ >>> model.fit(tf_dataset) # doctest: +SKIP
+ ```
+
+## తరవాత ఏంటి?
+
+ఇప్పుడు మీరు 🤗 ట్రాన్స్ఫార్మర్స్ త్వరిత పర్యటనను పూర్తి చేసారు, మా గైడ్లను తనిఖీ చేయండి మరియు అనుకూల మోడల్ను వ్రాయడం, టాస్క్ కోసం మోడల్ను చక్కగా తీర్చిదిద్దడం మరియు స్క్రిప్ట్తో మోడల్కు శిక్షణ ఇవ్వడం వంటి మరింత నిర్దిష్టమైన పనులను ఎలా చేయాలో తెలుసుకోండి. 🤗 ట్రాన్స్ఫార్మర్స్ కోర్ కాన్సెప్ట్ల గురించి మరింత తెలుసుకోవడానికి మీకు ఆసక్తి ఉంటే, ఒక కప్పు కాఫీ తాగి, మా కాన్సెప్టువల్ గైడ్లను చూడండి!
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/tr/_toctree.yml b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/tr/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..8401da6e4eb0aedae36913b7e053f8cf842d9d3e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/tr/_toctree.yml
@@ -0,0 +1,4 @@
+- sections:
+ - local: index
+ title: 🤗 Transformers
+ title: Get started
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/tr/index.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/tr/index.md
new file mode 100644
index 0000000000000000000000000000000000000000..1b2c665e169d808e778852d5fb4292739ed43b6f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/tr/index.md
@@ -0,0 +1,295 @@
+
+
+# 🤗 Transformers
+
+[PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/) ve [JAX](https://jax.readthedocs.io/en/latest/) için son teknoloji makine öğrenimi.
+
+🤗 Transformers, güncel önceden eğitilmiş (pretrained) modelleri indirmenizi ve eğitmenizi kolaylaştıran API'ler ve araçlar sunar. Önceden eğitilmiş modeller kullanarak, hesaplama maliyetlerinizi ve karbon ayak izinizi azaltabilir, ve sıfırdan bir modeli eğitmek için gereken zaman ve kaynaklardan tasarruf edebilirsiniz. Bu modeller farklı modalitelerde ortak görevleri destekler. Örneğin:
+
+📝 **Doğal Dil İşleme**: metin sınıflandırma, adlandırılmış varlık tanıma, soru cevaplama, dil modelleme, özetleme, çeviri, çoktan seçmeli ve metin oluşturma.
+
+
+## İçindekiler
+
+Dokümantasyon, beş bölüme ayrılmıştır:
+
+- **BAŞLARKEN**, kütüphanenin hızlı bir turunu ve çalışmaya başlamak için kurulum talimatlarını sağlar.
+- **ÖĞRETİCİLER**, başlangıç yapmak için harika bir yerdir. Bu bölüm, kütüphane kullanmaya başlamak için ihtiyacınız olan temel becerileri kazanmanıza yardımcı olacaktır.
+- **NASIL YAPILIR KILAVUZLARI**, önceden eğitilmiş bir modele dil modellemesi için ince ayar (fine-tuning) yapmak veya özel bir model yazmak, ve paylaşmak gibi belirli bir hedefe nasıl ulaşılacağını gösterir.
+- **KAVRAMSAL REHBERLER**, modellerin, görevlerin ve 🤗 Transformers tasarım felsefesinin temel kavramları ve fikirleri hakkında daha fazla tartışma ve açıklama sunar.
+- **API** tüm sınıfları (class) ve fonksiyonları (functions) açıklar:
+
+ - **ANA SINIFLAR**, yapılandırma, model, tokenizer ve pipeline gibi en önemli sınıfları (classes) ayrıntılandırır.
+ - **MODELLER**, kütüphanede kullanılan her modelle ilgili sınıfları ve fonksiyonları detaylı olarak inceler.
+ - **DAHİLİ YARDIMCILAR**, kullanılan yardımcı sınıfları ve fonksiyonları detaylı olarak inceler.
+
+## Desteklenen Modeller ve Çerçeveler
+
+Aşağıdaki tablo, her bir model için kütüphanede yer alan mevcut desteği temsil etmektedir. Her bir model için bir Python tokenizer'ına ("slow" olarak adlandırılır) sahip olup olmadıkları, 🤗 Tokenizers kütüphanesi tarafından desteklenen hızlı bir tokenizer'a sahip olup olmadıkları, Jax (Flax aracılığıyla), PyTorch ve/veya TensorFlow'da destek olup olmadıklarını göstermektedir.
+
+
+
+| Model | PyTorch support | TensorFlow support | Flax Support |
+|:------------------------------------------------------------------------:|:---------------:|:------------------:|:------------:|
+| [ALBERT](model_doc/albert) | ✅ | ✅ | ✅ |
+| [ALIGN](model_doc/align) | ✅ | ❌ | ❌ |
+| [AltCLIP](model_doc/altclip) | ✅ | ❌ | ❌ |
+| [Audio Spectrogram Transformer](model_doc/audio-spectrogram-transformer) | ✅ | ❌ | ❌ |
+| [Autoformer](model_doc/autoformer) | ✅ | ❌ | ❌ |
+| [Bark](model_doc/bark) | ✅ | ❌ | ❌ |
+| [BART](model_doc/bart) | ✅ | ✅ | ✅ |
+| [BARThez](model_doc/barthez) | ✅ | ✅ | ✅ |
+| [BARTpho](model_doc/bartpho) | ✅ | ✅ | ✅ |
+| [BEiT](model_doc/beit) | ✅ | ❌ | ✅ |
+| [BERT](model_doc/bert) | ✅ | ✅ | ✅ |
+| [Bert Generation](model_doc/bert-generation) | ✅ | ❌ | ❌ |
+| [BertJapanese](model_doc/bert-japanese) | ✅ | ✅ | ✅ |
+| [BERTweet](model_doc/bertweet) | ✅ | ✅ | ✅ |
+| [BigBird](model_doc/big_bird) | ✅ | ❌ | ✅ |
+| [BigBird-Pegasus](model_doc/bigbird_pegasus) | ✅ | ❌ | ❌ |
+| [BioGpt](model_doc/biogpt) | ✅ | ❌ | ❌ |
+| [BiT](model_doc/bit) | ✅ | ❌ | ❌ |
+| [Blenderbot](model_doc/blenderbot) | ✅ | ✅ | ✅ |
+| [BlenderbotSmall](model_doc/blenderbot-small) | ✅ | ✅ | ✅ |
+| [BLIP](model_doc/blip) | ✅ | ✅ | ❌ |
+| [BLIP-2](model_doc/blip-2) | ✅ | ❌ | ❌ |
+| [BLOOM](model_doc/bloom) | ✅ | ❌ | ✅ |
+| [BORT](model_doc/bort) | ✅ | ✅ | ✅ |
+| [BridgeTower](model_doc/bridgetower) | ✅ | ❌ | ❌ |
+| [BROS](model_doc/bros) | ✅ | ❌ | ❌ |
+| [ByT5](model_doc/byt5) | ✅ | ✅ | ✅ |
+| [CamemBERT](model_doc/camembert) | ✅ | ✅ | ❌ |
+| [CANINE](model_doc/canine) | ✅ | ❌ | ❌ |
+| [Chinese-CLIP](model_doc/chinese_clip) | ✅ | ❌ | ❌ |
+| [CLAP](model_doc/clap) | ✅ | ❌ | ❌ |
+| [CLIP](model_doc/clip) | ✅ | ✅ | ✅ |
+| [CLIPSeg](model_doc/clipseg) | ✅ | ❌ | ❌ |
+| [CodeGen](model_doc/codegen) | ✅ | ❌ | ❌ |
+| [CodeLlama](model_doc/code_llama) | ✅ | ❌ | ❌ |
+| [Conditional DETR](model_doc/conditional_detr) | ✅ | ❌ | ❌ |
+| [ConvBERT](model_doc/convbert) | ✅ | ✅ | ❌ |
+| [ConvNeXT](model_doc/convnext) | ✅ | ✅ | ❌ |
+| [ConvNeXTV2](model_doc/convnextv2) | ✅ | ❌ | ❌ |
+| [CPM](model_doc/cpm) | ✅ | ✅ | ✅ |
+| [CPM-Ant](model_doc/cpmant) | ✅ | ❌ | ❌ |
+| [CTRL](model_doc/ctrl) | ✅ | ✅ | ❌ |
+| [CvT](model_doc/cvt) | ✅ | ✅ | ❌ |
+| [Data2VecAudio](model_doc/data2vec) | ✅ | ❌ | ❌ |
+| [Data2VecText](model_doc/data2vec) | ✅ | ❌ | ❌ |
+| [Data2VecVision](model_doc/data2vec) | ✅ | ✅ | ❌ |
+| [DeBERTa](model_doc/deberta) | ✅ | ✅ | ❌ |
+| [DeBERTa-v2](model_doc/deberta-v2) | ✅ | ✅ | ❌ |
+| [Decision Transformer](model_doc/decision_transformer) | ✅ | ❌ | ❌ |
+| [Deformable DETR](model_doc/deformable_detr) | ✅ | ❌ | ❌ |
+| [DeiT](model_doc/deit) | ✅ | ✅ | ❌ |
+| [DePlot](model_doc/deplot) | ✅ | ❌ | ❌ |
+| [DETA](model_doc/deta) | ✅ | ❌ | ❌ |
+| [DETR](model_doc/detr) | ✅ | ❌ | ❌ |
+| [DialoGPT](model_doc/dialogpt) | ✅ | ✅ | ✅ |
+| [DiNAT](model_doc/dinat) | ✅ | ❌ | ❌ |
+| [DINOv2](model_doc/dinov2) | ✅ | ❌ | ❌ |
+| [DistilBERT](model_doc/distilbert) | ✅ | ✅ | ✅ |
+| [DiT](model_doc/dit) | ✅ | ❌ | ✅ |
+| [DonutSwin](model_doc/donut) | ✅ | ❌ | ❌ |
+| [DPR](model_doc/dpr) | ✅ | ✅ | ❌ |
+| [DPT](model_doc/dpt) | ✅ | ❌ | ❌ |
+| [EfficientFormer](model_doc/efficientformer) | ✅ | ✅ | ❌ |
+| [EfficientNet](model_doc/efficientnet) | ✅ | ❌ | ❌ |
+| [ELECTRA](model_doc/electra) | ✅ | ✅ | ✅ |
+| [EnCodec](model_doc/encodec) | ✅ | ❌ | ❌ |
+| [Encoder decoder](model_doc/encoder-decoder) | ✅ | ✅ | ✅ |
+| [ERNIE](model_doc/ernie) | ✅ | ❌ | ❌ |
+| [ErnieM](model_doc/ernie_m) | ✅ | ❌ | ❌ |
+| [ESM](model_doc/esm) | ✅ | ✅ | ❌ |
+| [FairSeq Machine-Translation](model_doc/fsmt) | ✅ | ❌ | ❌ |
+| [Falcon](model_doc/falcon) | ✅ | ❌ | ❌ |
+| [FLAN-T5](model_doc/flan-t5) | ✅ | ✅ | ✅ |
+| [FLAN-UL2](model_doc/flan-ul2) | ✅ | ✅ | ✅ |
+| [FlauBERT](model_doc/flaubert) | ✅ | ✅ | ❌ |
+| [FLAVA](model_doc/flava) | ✅ | ❌ | ❌ |
+| [FNet](model_doc/fnet) | ✅ | ❌ | ❌ |
+| [FocalNet](model_doc/focalnet) | ✅ | ❌ | ❌ |
+| [Funnel Transformer](model_doc/funnel) | ✅ | ✅ | ❌ |
+| [Fuyu](model_doc/fuyu) | ✅ | ❌ | ❌ |
+| [GIT](model_doc/git) | ✅ | ❌ | ❌ |
+| [GLPN](model_doc/glpn) | ✅ | ❌ | ❌ |
+| [GPT Neo](model_doc/gpt_neo) | ✅ | ❌ | ✅ |
+| [GPT NeoX](model_doc/gpt_neox) | ✅ | ❌ | ❌ |
+| [GPT NeoX Japanese](model_doc/gpt_neox_japanese) | ✅ | ❌ | ❌ |
+| [GPT-J](model_doc/gptj) | ✅ | ✅ | ✅ |
+| [GPT-Sw3](model_doc/gpt-sw3) | ✅ | ✅ | ✅ |
+| [GPTBigCode](model_doc/gpt_bigcode) | ✅ | ❌ | ❌ |
+| [GPTSAN-japanese](model_doc/gptsan-japanese) | ✅ | ❌ | ❌ |
+| [Graphormer](model_doc/graphormer) | ✅ | ❌ | ❌ |
+| [GroupViT](model_doc/groupvit) | ✅ | ✅ | ❌ |
+| [HerBERT](model_doc/herbert) | ✅ | ✅ | ✅ |
+| [Hubert](model_doc/hubert) | ✅ | ✅ | ❌ |
+| [I-BERT](model_doc/ibert) | ✅ | ❌ | ❌ |
+| [IDEFICS](model_doc/idefics) | ✅ | ❌ | ❌ |
+| [ImageGPT](model_doc/imagegpt) | ✅ | ❌ | ❌ |
+| [Informer](model_doc/informer) | ✅ | ❌ | ❌ |
+| [InstructBLIP](model_doc/instructblip) | ✅ | ❌ | ❌ |
+| [Jukebox](model_doc/jukebox) | ✅ | ❌ | ❌ |
+| [LayoutLM](model_doc/layoutlm) | ✅ | ✅ | ❌ |
+| [LayoutLMv2](model_doc/layoutlmv2) | ✅ | ❌ | ❌ |
+| [LayoutLMv3](model_doc/layoutlmv3) | ✅ | ✅ | ❌ |
+| [LayoutXLM](model_doc/layoutxlm) | ✅ | ❌ | ❌ |
+| [LED](model_doc/led) | ✅ | ✅ | ❌ |
+| [LeViT](model_doc/levit) | ✅ | ❌ | ❌ |
+| [LiLT](model_doc/lilt) | ✅ | ❌ | ❌ |
+| [LLaMA](model_doc/llama) | ✅ | ❌ | ❌ |
+| [Llama2](model_doc/llama2) | ✅ | ❌ | ❌ |
+| [Longformer](model_doc/longformer) | ✅ | ✅ | ❌ |
+| [LongT5](model_doc/longt5) | ✅ | ❌ | ✅ |
+| [LUKE](model_doc/luke) | ✅ | ❌ | ❌ |
+| [LXMERT](model_doc/lxmert) | ✅ | ✅ | ❌ |
+| [M-CTC-T](model_doc/mctct) | ✅ | ❌ | ❌ |
+| [M2M100](model_doc/m2m_100) | ✅ | ❌ | ❌ |
+| [Marian](model_doc/marian) | ✅ | ✅ | ✅ |
+| [MarkupLM](model_doc/markuplm) | ✅ | ❌ | ❌ |
+| [Mask2Former](model_doc/mask2former) | ✅ | ❌ | ❌ |
+| [MaskFormer](model_doc/maskformer) | ✅ | ❌ | ❌ |
+| [MatCha](model_doc/matcha) | ✅ | ❌ | ❌ |
+| [mBART](model_doc/mbart) | ✅ | ✅ | ✅ |
+| [mBART-50](model_doc/mbart50) | ✅ | ✅ | ✅ |
+| [MEGA](model_doc/mega) | ✅ | ❌ | ❌ |
+| [Megatron-BERT](model_doc/megatron-bert) | ✅ | ❌ | ❌ |
+| [Megatron-GPT2](model_doc/megatron_gpt2) | ✅ | ✅ | ✅ |
+| [MGP-STR](model_doc/mgp-str) | ✅ | ❌ | ❌ |
+| [Mistral](model_doc/mistral) | ✅ | ❌ | ❌ |
+| [mLUKE](model_doc/mluke) | ✅ | ❌ | ❌ |
+| [MMS](model_doc/mms) | ✅ | ✅ | ✅ |
+| [MobileBERT](model_doc/mobilebert) | ✅ | ✅ | ❌ |
+| [MobileNetV1](model_doc/mobilenet_v1) | ✅ | ❌ | ❌ |
+| [MobileNetV2](model_doc/mobilenet_v2) | ✅ | ❌ | ❌ |
+| [MobileViT](model_doc/mobilevit) | ✅ | ✅ | ❌ |
+| [MobileViTV2](model_doc/mobilevitv2) | ✅ | ❌ | ❌ |
+| [MPNet](model_doc/mpnet) | ✅ | ✅ | ❌ |
+| [MPT](model_doc/mpt) | ✅ | ❌ | ❌ |
+| [MRA](model_doc/mra) | ✅ | ❌ | ❌ |
+| [MT5](model_doc/mt5) | ✅ | ✅ | ✅ |
+| [MusicGen](model_doc/musicgen) | ✅ | ❌ | ❌ |
+| [MVP](model_doc/mvp) | ✅ | ❌ | ❌ |
+| [NAT](model_doc/nat) | ✅ | ❌ | ❌ |
+| [Nezha](model_doc/nezha) | ✅ | ❌ | ❌ |
+| [NLLB](model_doc/nllb) | ✅ | ❌ | ❌ |
+| [NLLB-MOE](model_doc/nllb-moe) | ✅ | ❌ | ❌ |
+| [Nougat](model_doc/nougat) | ✅ | ✅ | ✅ |
+| [Nyströmformer](model_doc/nystromformer) | ✅ | ❌ | ❌ |
+| [OneFormer](model_doc/oneformer) | ✅ | ❌ | ❌ |
+| [OpenAI GPT](model_doc/openai-gpt) | ✅ | ✅ | ❌ |
+| [OpenAI GPT-2](model_doc/gpt2) | ✅ | ✅ | ✅ |
+| [OpenLlama](model_doc/open-llama) | ✅ | ❌ | ❌ |
+| [OPT](model_doc/opt) | ✅ | ✅ | ✅ |
+| [OWL-ViT](model_doc/owlvit) | ✅ | ❌ | ❌ |
+| [OWLv2](model_doc/owlv2) | ✅ | ❌ | ❌ |
+| [Pegasus](model_doc/pegasus) | ✅ | ✅ | ✅ |
+| [PEGASUS-X](model_doc/pegasus_x) | ✅ | ❌ | ❌ |
+| [Perceiver](model_doc/perceiver) | ✅ | ❌ | ❌ |
+| [Persimmon](model_doc/persimmon) | ✅ | ❌ | ❌ |
+| [PhoBERT](model_doc/phobert) | ✅ | ✅ | ✅ |
+| [Pix2Struct](model_doc/pix2struct) | ✅ | ❌ | ❌ |
+| [PLBart](model_doc/plbart) | ✅ | ❌ | ❌ |
+| [PoolFormer](model_doc/poolformer) | ✅ | ❌ | ❌ |
+| [Pop2Piano](model_doc/pop2piano) | ✅ | ❌ | ❌ |
+| [ProphetNet](model_doc/prophetnet) | ✅ | ❌ | ❌ |
+| [PVT](model_doc/pvt) | ✅ | ❌ | ❌ |
+| [QDQBert](model_doc/qdqbert) | ✅ | ❌ | ❌ |
+| [RAG](model_doc/rag) | ✅ | ✅ | ❌ |
+| [REALM](model_doc/realm) | ✅ | ❌ | ❌ |
+| [Reformer](model_doc/reformer) | ✅ | ❌ | ❌ |
+| [RegNet](model_doc/regnet) | ✅ | ✅ | ✅ |
+| [RemBERT](model_doc/rembert) | ✅ | ✅ | ❌ |
+| [ResNet](model_doc/resnet) | ✅ | ✅ | ✅ |
+| [RetriBERT](model_doc/retribert) | ✅ | ❌ | ❌ |
+| [RoBERTa](model_doc/roberta) | ✅ | ✅ | ✅ |
+| [RoBERTa-PreLayerNorm](model_doc/roberta-prelayernorm) | ✅ | ✅ | ✅ |
+| [RoCBert](model_doc/roc_bert) | ✅ | ❌ | ❌ |
+| [RoFormer](model_doc/roformer) | ✅ | ✅ | ✅ |
+| [RWKV](model_doc/rwkv) | ✅ | ❌ | ❌ |
+| [SAM](model_doc/sam) | ✅ | ✅ | ❌ |
+| [SeamlessM4T](model_doc/seamless_m4t) | ✅ | ❌ | ❌ |
+| [SegFormer](model_doc/segformer) | ✅ | ✅ | ❌ |
+| [SEW](model_doc/sew) | ✅ | ❌ | ❌ |
+| [SEW-D](model_doc/sew-d) | ✅ | ❌ | ❌ |
+| [Speech Encoder decoder](model_doc/speech-encoder-decoder) | ✅ | ❌ | ✅ |
+| [Speech2Text](model_doc/speech_to_text) | ✅ | ✅ | ❌ |
+| [SpeechT5](model_doc/speecht5) | ✅ | ❌ | ❌ |
+| [Splinter](model_doc/splinter) | ✅ | ❌ | ❌ |
+| [SqueezeBERT](model_doc/squeezebert) | ✅ | ❌ | ❌ |
+| [SwiftFormer](model_doc/swiftformer) | ✅ | ❌ | ❌ |
+| [Swin Transformer](model_doc/swin) | ✅ | ✅ | ❌ |
+| [Swin Transformer V2](model_doc/swinv2) | ✅ | ❌ | ❌ |
+| [Swin2SR](model_doc/swin2sr) | ✅ | ❌ | ❌ |
+| [SwitchTransformers](model_doc/switch_transformers) | ✅ | ❌ | ❌ |
+| [T5](model_doc/t5) | ✅ | ✅ | ✅ |
+| [T5v1.1](model_doc/t5v1.1) | ✅ | ✅ | ✅ |
+| [Table Transformer](model_doc/table-transformer) | ✅ | ❌ | ❌ |
+| [TAPAS](model_doc/tapas) | ✅ | ✅ | ❌ |
+| [TAPEX](model_doc/tapex) | ✅ | ✅ | ✅ |
+| [Time Series Transformer](model_doc/time_series_transformer) | ✅ | ❌ | ❌ |
+| [TimeSformer](model_doc/timesformer) | ✅ | ❌ | ❌ |
+| [Trajectory Transformer](model_doc/trajectory_transformer) | ✅ | ❌ | ❌ |
+| [Transformer-XL](model_doc/transfo-xl) | ✅ | ✅ | ❌ |
+| [TrOCR](model_doc/trocr) | ✅ | ❌ | ❌ |
+| [TVLT](model_doc/tvlt) | ✅ | ❌ | ❌ |
+| [UL2](model_doc/ul2) | ✅ | ✅ | ✅ |
+| [UMT5](model_doc/umt5) | ✅ | ❌ | ❌ |
+| [UniSpeech](model_doc/unispeech) | ✅ | ❌ | ❌ |
+| [UniSpeechSat](model_doc/unispeech-sat) | ✅ | ❌ | ❌ |
+| [UPerNet](model_doc/upernet) | ✅ | ❌ | ❌ |
+| [VAN](model_doc/van) | ✅ | ❌ | ❌ |
+| [VideoMAE](model_doc/videomae) | ✅ | ❌ | ❌ |
+| [ViLT](model_doc/vilt) | ✅ | ❌ | ❌ |
+| [Vision Encoder decoder](model_doc/vision-encoder-decoder) | ✅ | ✅ | ✅ |
+| [VisionTextDualEncoder](model_doc/vision-text-dual-encoder) | ✅ | ✅ | ✅ |
+| [VisualBERT](model_doc/visual_bert) | ✅ | ❌ | ❌ |
+| [ViT](model_doc/vit) | ✅ | ✅ | ✅ |
+| [ViT Hybrid](model_doc/vit_hybrid) | ✅ | ❌ | ❌ |
+| [VitDet](model_doc/vitdet) | ✅ | ❌ | ❌ |
+| [ViTMAE](model_doc/vit_mae) | ✅ | ✅ | ❌ |
+| [ViTMatte](model_doc/vitmatte) | ✅ | ❌ | ❌ |
+| [ViTMSN](model_doc/vit_msn) | ✅ | ❌ | ❌ |
+| [VITS](model_doc/vits) | ✅ | ❌ | ❌ |
+| [ViViT](model_doc/vivit) | ✅ | ❌ | ❌ |
+| [Wav2Vec2](model_doc/wav2vec2) | ✅ | ✅ | ✅ |
+| [Wav2Vec2-Conformer](model_doc/wav2vec2-conformer) | ✅ | ❌ | ❌ |
+| [Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme) | ✅ | ✅ | ✅ |
+| [WavLM](model_doc/wavlm) | ✅ | ❌ | ❌ |
+| [Whisper](model_doc/whisper) | ✅ | ✅ | ✅ |
+| [X-CLIP](model_doc/xclip) | ✅ | ❌ | ❌ |
+| [X-MOD](model_doc/xmod) | ✅ | ❌ | ❌ |
+| [XGLM](model_doc/xglm) | ✅ | ✅ | ✅ |
+| [XLM](model_doc/xlm) | ✅ | ✅ | ❌ |
+| [XLM-ProphetNet](model_doc/xlm-prophetnet) | ✅ | ❌ | ❌ |
+| [XLM-RoBERTa](model_doc/xlm-roberta) | ✅ | ✅ | ✅ |
+| [XLM-RoBERTa-XL](model_doc/xlm-roberta-xl) | ✅ | ❌ | ❌ |
+| [XLM-V](model_doc/xlm-v) | ✅ | ✅ | ✅ |
+| [XLNet](model_doc/xlnet) | ✅ | ✅ | ❌ |
+| [XLS-R](model_doc/xls_r) | ✅ | ✅ | ✅ |
+| [XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2) | ✅ | ✅ | ✅ |
+| [YOLOS](model_doc/yolos) | ✅ | ❌ | ❌ |
+| [YOSO](model_doc/yoso) | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/_toctree.yml b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..2cce86b6592484acedc2bc10b7dae7e01381ee97
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/_toctree.yml
@@ -0,0 +1,172 @@
+- sections:
+ - local: index
+ title: 🤗 Transformers 简介
+ - local: quicktour
+ title: 快速上手
+ - local: installation
+ title: 安装
+ title: 开始使用
+- sections:
+ - local: pipeline_tutorial
+ title: 使用pipelines进行推理
+ - local: autoclass_tutorial
+ title: 使用AutoClass编写可移植的代码
+ - local: preprocessing
+ title: 预处理数据
+ - local: training
+ title: 微调预训练模型
+ - local: run_scripts
+ title: 通过脚本训练模型
+ - local: accelerate
+ title: 使用🤗Accelerate进行分布式训练
+ - local: peft
+ title: 使用🤗 PEFT加载和训练adapters
+ - local: model_sharing
+ title: 分享您的模型
+ - local: agents
+ title: 智能体和工具
+ - local: agents_advanced
+ title: 智能体,超强版 - 多智能体、外部工具等
+ - local: llm_tutorial
+ title: 使用LLMs进行生成
+ title: 教程
+- sections:
+ - isExpanded: false
+ sections:
+ - local: tasks/asr
+ title: 自动语音识别
+- sections:
+ - local: fast_tokenizers
+ title: 使用 🤗 Tokenizers 中的分词器
+ - local: multilingual
+ title: 使用多语言模型进行推理
+ - local: create_a_model
+ title: 使用特定于模型的 API
+ - local: custom_models
+ title: 共享自定义模型
+ - local: chat_templating
+ title: 聊天模型的模板
+ - local: serialization
+ title: 导出为 ONNX
+ - local: tflite
+ title: 导出为 TFLite
+ - local: torchscript
+ title: 导出为 TorchScript
+ - local: benchmarks
+ title: 对模型进行基准测试
+ - local: gguf
+ title: 与 GGUF 格式的互操作性
+ - local: tiktoken
+ title: 与 Tiktoken 文件的互操作性
+ - local: community
+ title: 社区资源
+ title: 开发者指南
+- sections:
+ - local: performance
+ title: 综述
+ - sections:
+ - local: fsdp
+ title: 完全分片数据并行
+ - local: perf_train_special
+ title: 在 Apple silicon 芯片上进行 PyTorch 训练
+ - local: perf_infer_gpu_multi
+ title: 多GPU推理
+ - local: perf_train_cpu
+ title: 在CPU上进行高效训练
+ - local: perf_hardware
+ title: 用于训练的定制硬件
+ - local: hpo_train
+ title: 使用Trainer API 进行超参数搜索
+ title: 高效训练技术
+ - local: big_models
+ title: 实例化大模型
+ - local: debugging
+ title: 问题定位及解决
+ - local: tf_xla
+ title: TensorFlow模型的XLA集成
+ - local: perf_torch_compile
+ title: 使用 `torch.compile()` 优化推理
+ title: 性能和可扩展性
+- sections:
+ - local: contributing
+ title: 如何为 🤗 Transformers 做贡献?
+ - local: add_new_pipeline
+ title: 如何将流水线添加到 🤗 Transformers?
+ title: 贡献
+- sections:
+ - local: philosophy
+ title: Transformers的设计理念
+ - local: task_summary
+ title: 🤗Transformers能做什么
+ - local: tokenizer_summary
+ title: 分词器的摘要
+ - local: attention
+ title: 注意力机制
+ - local: bertology
+ title: 基于BERT进行的相关研究
+ title: 概念指南
+- sections:
+ - sections:
+ - local: main_classes/agent
+ title: 智能体和工具
+ - local: main_classes/callback
+ title: Callbacks
+ - local: main_classes/configuration
+ title: Configuration
+ - local: main_classes/data_collator
+ title: Data Collator
+ - local: main_classes/keras_callbacks
+ title: Keras callbacks
+ - local: main_classes/logging
+ title: Logging
+ - local: main_classes/model
+ title: 模型
+ - local: main_classes/text_generation
+ title: 文本生成
+ - local: main_classes/onnx
+ title: ONNX
+ - local: main_classes/optimizer_schedules
+ title: Optimization
+ - local: main_classes/output
+ title: 模型输出
+ - local: main_classes/pipelines
+ title: Pipelines
+ - local: main_classes/processors
+ title: Processors
+ - local: main_classes/quantization
+ title: Quantization
+ - local: main_classes/tokenizer
+ title: Tokenizer
+ - local: main_classes/trainer
+ title: Trainer
+ - local: main_classes/deepspeed
+ title: DeepSpeed集成
+ - local: main_classes/feature_extractor
+ title: Feature Extractor
+ - local: main_classes/image_processor
+ title: Image Processor
+ title: 主要类
+ - sections:
+ - local: internal/modeling_utils
+ title: 自定义层和工具
+ - local: internal/pipelines_utils
+ title: pipelines工具
+ - local: internal/tokenization_utils
+ title: Tokenizers工具
+ - local: internal/trainer_utils
+ title: 训练器工具
+ - local: internal/generation_utils
+ title: 生成工具
+ - local: internal/image_processing_utils
+ title: 图像处理工具
+ - local: internal/audio_utils
+ title: 音频处理工具
+ - local: internal/file_utils
+ title: 通用工具
+ - local: internal/time_series_utils
+ title: 时序数据工具
+ title: 内部辅助工具
+ title: 应用程序接口 (API)
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/accelerate.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/accelerate.md
new file mode 100644
index 0000000000000000000000000000000000000000..12c626199477dd14cfc322f642909132832cf258
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/accelerate.md
@@ -0,0 +1,132 @@
+
+
+# 🤗 加速分布式训练
+
+随着模型变得越来越大,并行性已经成为在有限硬件上训练更大模型和加速训练速度的策略,增加了数个数量级。在Hugging Face,我们创建了[🤗 加速](https://huggingface.co/docs/accelerate)库,以帮助用户在任何类型的分布式设置上轻松训练🤗 Transformers模型,无论是在一台机器上的多个GPU还是在多个机器上的多个GPU。在本教程中,了解如何自定义您的原生PyTorch训练循环,以启用分布式环境中的训练。
+
+## 设置
+
+通过安装🤗 加速开始:
+
+```bash
+pip install accelerate
+```
+
+然后导入并创建[`~accelerate.Accelerator`]对象。[`~accelerate.Accelerator`]将自动检测您的分布式设置类型,并初始化所有必要的训练组件。您不需要显式地将模型放在设备上。
+
+```py
+>>> from accelerate import Accelerator
+
+>>> accelerator = Accelerator()
+```
+
+## 准备加速
+
+下一步是将所有相关的训练对象传递给[`~accelerate.Accelerator.prepare`]方法。这包括您的训练和评估DataLoader、一个模型和一个优化器:
+
+```py
+>>> train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
+... train_dataloader, eval_dataloader, model, optimizer
+... )
+```
+
+## 反向传播
+
+最后一步是用🤗 加速的[`~accelerate.Accelerator.backward`]方法替换训练循环中的典型`loss.backward()`:
+
+```py
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... outputs = model(**batch)
+... loss = outputs.loss
+... accelerator.backward(loss)
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+如您在下面的代码中所见,您只需要添加四行额外的代码到您的训练循环中即可启用分布式训练!
+
+```diff
++ from accelerate import Accelerator
+ from transformers import AdamW, AutoModelForSequenceClassification, get_scheduler
+
++ accelerator = Accelerator()
+
+ model = AutoModelForSequenceClassification.from_pretrained(checkpoint, num_labels=2)
+ optimizer = AdamW(model.parameters(), lr=3e-5)
+
+- device = torch.device("cuda") if torch.cuda.is_available() else torch.device("cpu")
+- model.to(device)
+
++ train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
++ train_dataloader, eval_dataloader, model, optimizer
++ )
+
+ num_epochs = 3
+ num_training_steps = num_epochs * len(train_dataloader)
+ lr_scheduler = get_scheduler(
+ "linear",
+ optimizer=optimizer,
+ num_warmup_steps=0,
+ num_training_steps=num_training_steps
+ )
+
+ progress_bar = tqdm(range(num_training_steps))
+
+ model.train()
+ for epoch in range(num_epochs):
+ for batch in train_dataloader:
+- batch = {k: v.to(device) for k, v in batch.items()}
+ outputs = model(**batch)
+ loss = outputs.loss
+- loss.backward()
++ accelerator.backward(loss)
+
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ progress_bar.update(1)
+```
+
+## 训练
+
+在添加了相关代码行后,可以在脚本或笔记本(如Colaboratory)中启动训练。
+
+### 用脚本训练
+
+如果您从脚本中运行训练,请运行以下命令以创建和保存配置文件:
+
+```bash
+accelerate config
+```
+
+然后使用以下命令启动训练:
+
+```bash
+accelerate launch train.py
+```
+
+### 用笔记本训练
+
+🤗 加速还可以在笔记本中运行,如果您计划使用Colaboratory的TPU,则可在其中运行。将负责训练的所有代码包装在一个函数中,并将其传递给[`~accelerate.notebook_launcher`]:
+
+```py
+>>> from accelerate import notebook_launcher
+
+>>> notebook_launcher(training_function)
+```
+
+有关🤗 加速及其丰富功能的更多信息,请参阅[文档](https://huggingface.co/docs/accelerate)。
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/add_new_pipeline.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/add_new_pipeline.md
new file mode 100644
index 0000000000000000000000000000000000000000..57fd53636b0a1360f44ecf9af9f94c37d1e84f45
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/add_new_pipeline.md
@@ -0,0 +1,238 @@
+
+
+# 如何创建自定义流水线?
+
+在本指南中,我们将演示如何创建一个自定义流水线并分享到 [Hub](https://hf.co/models),或将其添加到 🤗 Transformers 库中。
+
+首先,你需要决定流水线将能够接受的原始条目。它可以是字符串、原始字节、字典或任何看起来最可能是期望的输入。
+尽量保持输入为纯 Python 语言,因为这样可以更容易地实现兼容性(甚至通过 JSON 在其他语言之间)。
+这些将是流水线 (`preprocess`) 的 `inputs`。
+
+然后定义 `outputs`。与 `inputs` 相同的策略。越简单越好。这些将是 `postprocess` 方法的输出。
+
+首先继承基类 `Pipeline`,其中包含实现 `preprocess`、`_forward`、`postprocess` 和 `_sanitize_parameters` 所需的 4 个方法。
+
+```python
+from transformers import Pipeline
+
+
+class MyPipeline(Pipeline):
+ def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "maybe_arg" in kwargs:
+ preprocess_kwargs["maybe_arg"] = kwargs["maybe_arg"]
+ return preprocess_kwargs, {}, {}
+
+ def preprocess(self, inputs, maybe_arg=2):
+ model_input = Tensor(inputs["input_ids"])
+ return {"model_input": model_input}
+
+ def _forward(self, model_inputs):
+ # model_inputs == {"model_input": model_input}
+ outputs = self.model(**model_inputs)
+ # Maybe {"logits": Tensor(...)}
+ return outputs
+
+ def postprocess(self, model_outputs):
+ best_class = model_outputs["logits"].softmax(-1)
+ return best_class
+```
+
+这种分解的结构旨在为 CPU/GPU 提供相对无缝的支持,同时支持在不同线程上对 CPU 进行预处理/后处理。
+
+`preprocess` 将接受最初定义的输入,并将其转换为可供模型输入的内容。它可能包含更多信息,通常是一个 `Dict`。
+
+`_forward` 是实现细节,不应直接调用。`forward` 是首选的调用方法,因为它包含保障措施,以确保一切都在预期的设备上运作。
+如果任何内容与实际模型相关,它应该属于 `_forward` 方法,其他内容应该在 preprocess/postprocess 中。
+
+`postprocess` 方法将接受 `_forward` 的输出,并将其转换为之前确定的最终输出。
+
+`_sanitize_parameters` 存在是为了允许用户在任何时候传递任何参数,无论是在初始化时 `pipeline(...., maybe_arg=4)`
+还是在调用时 `pipe = pipeline(...); output = pipe(...., maybe_arg=4)`。
+
+`_sanitize_parameters` 的返回值是将直接传递给 `preprocess`、`_forward` 和 `postprocess` 的 3 个关键字参数字典。
+如果调用方没有使用任何额外参数调用,则不要填写任何内容。这样可以保留函数定义中的默认参数,这总是更"自然"的。
+
+在分类任务中,一个经典的例子是在后处理中使用 `top_k` 参数。
+
+```python
+>>> pipe = pipeline("my-new-task")
+>>> pipe("This is a test")
+[{"label": "1-star", "score": 0.8}, {"label": "2-star", "score": 0.1}, {"label": "3-star", "score": 0.05}
+{"label": "4-star", "score": 0.025}, {"label": "5-star", "score": 0.025}]
+
+>>> pipe("This is a test", top_k=2)
+[{"label": "1-star", "score": 0.8}, {"label": "2-star", "score": 0.1}]
+```
+
+为了实现这一点,我们将更新我们的 `postprocess` 方法,将默认参数设置为 `5`,
+并编辑 `_sanitize_parameters` 方法,以允许这个新参数。
+
+```python
+def postprocess(self, model_outputs, top_k=5):
+ best_class = model_outputs["logits"].softmax(-1)
+ # Add logic to handle top_k
+ return best_class
+
+
+def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "maybe_arg" in kwargs:
+ preprocess_kwargs["maybe_arg"] = kwargs["maybe_arg"]
+
+ postprocess_kwargs = {}
+ if "top_k" in kwargs:
+ postprocess_kwargs["top_k"] = kwargs["top_k"]
+ return preprocess_kwargs, {}, postprocess_kwargs
+```
+
+尽量保持简单输入/输出,最好是可 JSON 序列化的,因为这样可以使流水线的使用非常简单,而不需要用户了解新的对象类型。
+通常也相对常见地支持许多不同类型的参数以便使用(例如音频文件,可以是文件名、URL 或纯字节)。
+
+## 将其添加到支持的任务列表中
+
+要将你的 `new-task` 注册到支持的任务列表中,你需要将其添加到 `PIPELINE_REGISTRY` 中:
+
+```python
+from transformers.pipelines import PIPELINE_REGISTRY
+
+PIPELINE_REGISTRY.register_pipeline(
+ "new-task",
+ pipeline_class=MyPipeline,
+ pt_model=AutoModelForSequenceClassification,
+)
+```
+
+如果需要,你可以指定一个默认模型,此时它应该带有一个特定的修订版本(可以是分支名称或提交哈希,这里我们使用了 `"abcdef"`),以及类型:
+
+```python
+PIPELINE_REGISTRY.register_pipeline(
+ "new-task",
+ pipeline_class=MyPipeline,
+ pt_model=AutoModelForSequenceClassification,
+ default={"pt": ("user/awesome_model", "abcdef")},
+ type="text", # current support type: text, audio, image, multimodal
+)
+```
+
+## 在 Hub 上分享你的流水线
+
+要在 Hub 上分享你的自定义流水线,你只需要将 `Pipeline` 子类的自定义代码保存在一个 Python 文件中。
+例如,假设我们想使用一个自定义流水线进行句对分类,如下所示:
+
+```py
+import numpy as np
+
+from transformers import Pipeline
+
+
+def softmax(outputs):
+ maxes = np.max(outputs, axis=-1, keepdims=True)
+ shifted_exp = np.exp(outputs - maxes)
+ return shifted_exp / shifted_exp.sum(axis=-1, keepdims=True)
+
+
+class PairClassificationPipeline(Pipeline):
+ def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "second_text" in kwargs:
+ preprocess_kwargs["second_text"] = kwargs["second_text"]
+ return preprocess_kwargs, {}, {}
+
+ def preprocess(self, text, second_text=None):
+ return self.tokenizer(text, text_pair=second_text, return_tensors=self.framework)
+
+ def _forward(self, model_inputs):
+ return self.model(**model_inputs)
+
+ def postprocess(self, model_outputs):
+ logits = model_outputs.logits[0].numpy()
+ probabilities = softmax(logits)
+
+ best_class = np.argmax(probabilities)
+ label = self.model.config.id2label[best_class]
+ score = probabilities[best_class].item()
+ logits = logits.tolist()
+ return {"label": label, "score": score, "logits": logits}
+```
+
+这个实现与框架无关,适用于 PyTorch 和 TensorFlow 模型。如果我们将其保存在一个名为
+`pair_classification.py` 的文件中,然后我们可以像这样导入并注册它:
+
+```py
+from pair_classification import PairClassificationPipeline
+from transformers.pipelines import PIPELINE_REGISTRY
+from transformers import AutoModelForSequenceClassification, TFAutoModelForSequenceClassification
+
+PIPELINE_REGISTRY.register_pipeline(
+ "pair-classification",
+ pipeline_class=PairClassificationPipeline,
+ pt_model=AutoModelForSequenceClassification,
+ tf_model=TFAutoModelForSequenceClassification,
+)
+```
+
+完成这些步骤后,我们可以将其与预训练模型一起使用。例如,`sgugger/finetuned-bert-mrpc`
+已经在 MRPC 数据集上进行了微调,用于将句子对分类为是释义或不是释义。
+
+```py
+from transformers import pipeline
+
+classifier = pipeline("pair-classification", model="sgugger/finetuned-bert-mrpc")
+```
+
+然后,我们可以通过在 `Repository` 中使用 `save_pretrained` 方法将其分享到 Hub 上:
+
+```py
+from huggingface_hub import Repository
+
+repo = Repository("test-dynamic-pipeline", clone_from="{your_username}/test-dynamic-pipeline")
+classifier.save_pretrained("test-dynamic-pipeline")
+repo.push_to_hub()
+```
+
+这将会复制包含你定义的 `PairClassificationPipeline` 的文件到文件夹 `"test-dynamic-pipeline"` 中,
+同时保存流水线的模型和分词器,然后将所有内容推送到仓库 `{your_username}/test-dynamic-pipeline` 中。
+之后,只要提供选项 `trust_remote_code=True`,任何人都可以使用它:
+
+```py
+from transformers import pipeline
+
+classifier = pipeline(model="{your_username}/test-dynamic-pipeline", trust_remote_code=True)
+```
+
+## 将流水线添加到 🤗 Transformers
+
+如果你想将你的流水线贡献给 🤗 Transformers,你需要在 `pipelines` 子模块中添加一个新模块,
+其中包含你的流水线的代码,然后将其添加到 `pipelines/__init__.py` 中定义的任务列表中。
+
+然后,你需要添加测试。创建一个新文件 `tests/test_pipelines_MY_PIPELINE.py`,其中包含其他测试的示例。
+
+`run_pipeline_test` 函数将非常通用,并在每种可能的架构上运行小型随机模型,如 `model_mapping` 和 `tf_model_mapping` 所定义。
+
+这对于测试未来的兼容性非常重要,这意味着如果有人为 `XXXForQuestionAnswering` 添加了一个新模型,
+流水线测试将尝试在其上运行。由于模型是随机的,所以不可能检查实际值,这就是为什么有一个帮助函数 `ANY`,它只是尝试匹配流水线的输出类型。
+
+你还 **需要** 实现 2(最好是 4)个测试。
+
+- `test_small_model_pt`:为这个流水线定义一个小型模型(结果是否合理并不重要),并测试流水线的输出。
+ 结果应该与 `test_small_model_tf` 的结果相同。
+- `test_small_model_tf`:为这个流水线定义一个小型模型(结果是否合理并不重要),并测试流水线的输出。
+ 结果应该与 `test_small_model_pt` 的结果相同。
+- `test_large_model_pt`(可选):在一个真实的流水线上测试流水线,结果应该是有意义的。
+ 这些测试速度较慢,应该被如此标记。这里的目标是展示流水线,并确保在未来的发布中没有漂移。
+- `test_large_model_tf`(可选):在一个真实的流水线上测试流水线,结果应该是有意义的。
+ 这些测试速度较慢,应该被如此标记。这里的目标是展示流水线,并确保在未来的发布中没有漂移。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/agents.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/agents.md
new file mode 100644
index 0000000000000000000000000000000000000000..00fa74e65450259503cf5a0ccc0786b4449d7b45
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/agents.md
@@ -0,0 +1,427 @@
+
+# 智能体和工具
+
+[[在colab里打开]]
+
+### 什么是智能体 (Agent)?
+
+大型语言模型(LLM)经过 [因果语言建模训练](./tasks/language_modeling) 可以应对各种任务,但在一些基本任务(如逻辑推理、计算和搜索)上常常表现不佳。当它们被用在自己不擅长的领域时,往往无法生成我们期望的答案。
+
+为了解决这个问题,可以创建**智能体**.
+
+智能体是一个系统,它使用 LLM 作为引擎,并且能够访问称为**工具**的功能。
+
+这些**工具**是执行任务的函数,包含所有必要的描述信息,帮助智能体正确使用它们。
+
+智能体可以被编程为:
+- 一次性设计一系列工具并同时执行它们,像 [`CodeAgent`]
+- 一次执行一个工具,并等待每个工具的结果后再启动下一个,像 [`ReactJsonAgent`]
+
+### 智能体类型
+
+#### 代码智能体
+
+此智能体包含一个规划步骤,然后生成 Python 代码一次性执行所有任务。它原生支持处理不同输入和输出类型,因此推荐用于多模态任务。
+
+#### 推理智能体
+
+这是解决推理任务的首选代理,因为 ReAct 框架 ([Yao et al., 2022](https://huggingface.co/papers/2210.03629)) 使其在基于之前观察进行推理时非常高效。
+
+我们实现了两种版本的 ReactJsonAgent:
+- [`ReactJsonAgent`] 将工具调用作为 JSON 格式输出。
+- [`ReactCodeAgent`] 是 ReactJsonAgent 的一种新型,生成工具调用的代码块,对于具备强大编程能力的 LLM 非常适用。
+
+> [TIP]
+> 阅读 [Open-source LLMs as LangChain Agents](https://huggingface.co/blog/open-source-llms-as-agents) 博文,了解更多关于推理智能体的信息。
+
+
+
+
+
")
+
+client = InferenceClient(model="meta-llama/Meta-Llama-3-70B-Instruct")
+
+def llm_engine(messages, stop_sequences=["Task"]) -> str:
+ response = client.chat_completion(messages, stop=stop_sequences, max_tokens=1000)
+ answer = response.choices[0].message.content
+ return answer
+```
+
+您可以使用任何符合以下要求的 `llm_engine` 方法:
+1. [输入格式](./chat_templating)为 (`List[Dict[str, str]]`),并且返回一个字符串。
+2. 它在 `stop_sequences` 参数传递的序列处停止生成输出。
+
+此外,`llm_engine` 还可以接受一个 `grammar` 参数。如果在智能体初始化时指定了 `grammar`,则该参数将传递给 `llm_engine` 的调用,以允许[受限生成](https://huggingface.co/docs/text-generation-inference/conceptual/guidance),以强制生成格式正确的智能体输出。
+
+您还需要一个 `tools` 参数,它接受一个 `Tools` 列表 —— 可以是空列表。您也可以通过定义可选参数 `add_base_tools=True` 来将默认工具箱添加到工具列表中。
+
+现在,您可以创建一个智能体,例如 [`CodeAgent`],并运行它。您还可以创建一个 [`TransformersEngine`],使用 `transformers` 在本地机器上运行预初始化的推理管道。 为了方便起见,由于智能体行为通常需要更强大的模型,例如 `Llama-3.1-70B-Instruct`,它们目前较难在本地运行,我们还提供了 [`HfApiEngine`] 类,它在底层初始化了一个 `huggingface_hub.InferenceClient`。
+
+```python
+from transformers import CodeAgent, HfApiEngine
+
+llm_engine = HfApiEngine(model="meta-llama/Meta-Llama-3-70B-Instruct")
+agent = CodeAgent(tools=[], llm_engine=llm_engine, add_base_tools=True)
+
+agent.run(
+ "Could you translate this sentence from French, say it out loud and return the audio.",
+ sentence="Où est la boulangerie la plus proche?",
+)
+```
+
+当你急需某个东西时这将会很有用!
+您甚至可以将 `llm_engine` 参数留空,默认情况下会创建一个 [`HfApiEngine`]。
+
+```python
+from transformers import CodeAgent
+
+agent = CodeAgent(tools=[], add_base_tools=True)
+
+agent.run(
+ "Could you translate this sentence from French, say it out loud and give me the audio.",
+ sentence="Où est la boulangerie la plus proche?",
+)
+```
+
+请注意,我们使用了额外的 `sentence` 参数:您可以将文本作为附加参数传递给模型。
+
+您还可以使用这个来指定本地或远程文件的路径供模型使用:
+
+```py
+from transformers import ReactCodeAgent
+
+agent = ReactCodeAgent(tools=[], llm_engine=llm_engine, add_base_tools=True)
+
+agent.run("Why does Mike not know many people in New York?", audio="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/recording.mp3")
+```
+
+系统提示和输出解析器会自动定义,但您可以通过调用智能体的 `system_prompt_template` 来轻松查看它们。
+
+```python
+print(agent.system_prompt_template)
+```
+
+尽可能清楚地解释您要执行的任务非常重要。 每次 [`~Agent.run`] 操作都是独立的,并且由于智能体是由 LLM 驱动的,提示中的细微变化可能会导致完全不同的结果。
+您还可以连续运行多个任务,每次都会重新初始化智能体的 `agent.task` 和 `agent.logs` 属性。
+
+
+#### 代码执行
+
+Python 解释器在一组输入和工具上执行代码。 这应该是安全的,因为只能调用您提供的工具(特别是 Hugging Face 的工具)和 print 函数,因此您已经限制了可以执行的操作。
+
+Python 解释器默认不允许导入不在安全列表中的模块,因此大多数明显的攻击问题应该不成问题。 您仍然可以通过在 [`ReactCodeAgent`] 或 [`CodeAgent`] 初始化时通过 `additional_authorized_imports` 参数传递一个授权的模块列表来授权额外的导入:
+
+```py
+>>> from transformers import ReactCodeAgent
+
+>>> agent = ReactCodeAgent(tools=[], additional_authorized_imports=['requests', 'bs4'])
+>>> agent.run("Could you get me the title of the page at url 'https://huggingface.co/blog'?")
+
+(...)
+'Hugging Face – Blog'
+```
+
+如果有任何代码尝试执行非法操作,或者生成的代码出现常规 Python 错误,执行将停止。
+
+> [!WARNING]
+> 在使用大语言模型(LLM)生成代码时,生成的代码会被执行,避免导入或使用任何不安全的库或模块。
+
+### 系统提示
+
+智能体,或者说驱动智能体的 LLM,根据系统提示生成输出。系统提示可以定制并根据目标任务进行调整。例如,检查 [`ReactCodeAgent`] 的系统提示(以下版本经过简化)。
+
+```text
+You will be given a task to solve as best you can.
+You have access to the following tools:
+<>
+
+To solve the task, you must plan forward to proceed in a series of steps, in a cycle of 'Thought:', 'Code:', and 'Observation:' sequences.
+
+At each step, in the 'Thought:' sequence, you should first explain your reasoning towards solving the task, then the tools that you want to use.
+Then in the 'Code:' sequence, you should write the code in simple Python. The code sequence must end with '/End code' sequence.
+During each intermediate step, you can use 'print()' to save whatever important information you will then need.
+These print outputs will then be available in the 'Observation:' field, for using this information as input for the next step.
+
+In the end you have to return a final answer using the `final_answer` tool.
+
+Here are a few examples using notional tools:
+---
+{examples}
+
+Above example were using notional tools that might not exist for you. You only have acces to those tools:
+<>
+You also can perform computations in the python code you generate.
+
+Always provide a 'Thought:' and a 'Code:\n```py' sequence ending with '```' sequence. You MUST provide at least the 'Code:' sequence to move forward.
+
+Remember to not perform too many operations in a single code block! You should split the task into intermediate code blocks.
+Print results at the end of each step to save the intermediate results. Then use final_answer() to return the final result.
+
+Remember to make sure that variables you use are all defined.
+
+Now Begin!
+```
+
+系统提示包括:
+- 解释智能体应该如何工作以及工具的**介绍**。
+- 所有工具的描述由 `<>` 标记在运行时动态替换,这样智能体就知道可以使用哪些工具及其用途。
+ - 工具的描述来自工具的属性,`name`、`description`、`inputs` 和 `output_type`,以及一个简单的 `jinja2` 模板,您可以根据需要进行调整。
+- 期望的输出格式。
+
+您可以通过向 `system_prompt` 参数传递自定义提示来最大程度地提高灵活性,从而覆盖整个系统提示模板。
+
+```python
+from transformers import ReactJsonAgent
+from transformers.agents import PythonInterpreterTool
+
+agent = ReactJsonAgent(tools=[PythonInterpreterTool()], system_prompt="{your_custom_prompt}")
+```
+
+> [WARNING]
+> 必须在`template`中定义 `<>` 这个变量,以便智能体能够正确地识别并使用可用的工具
+
+
+### 检查智能体的运行
+
+以下是检查运行后发生了什么的一些有用属性:
+- `agent.logs` 存储了智能体的详细日志。每一步的所有内容都会存储在一个字典中,然后附加到 `agent.logs`。
+- 运行 `agent.write_inner_memory_from_logs()` 会从日志中创建智能体的内存,以便 LLM 查看,作为一系列聊天消息。此方法会遍历日志的每个步骤,只保存其感兴趣的消息:例如,它会单独保存系统提示和任务,然后为每个步骤保存 LLM 输出的消息,以及工具调用输出的消息。如果您想要更高层次的查看发生了什么,可以使用此方法 —— 但并不是每个日志都会被此方法转录。
+
+## 工具
+
+工具是智能体使用的基本功能。
+
+例如,您可以检查 [`PythonInterpreterTool`]:它有一个名称、描述、输入描述、输出类型和 `__call__` 方法来执行该操作。
+
+当智能体初始化时,工具属性会用来生成工具描述,然后将其嵌入到智能体的系统提示中,这让智能体知道可以使用哪些工具以及为什么使用它们。
+
+### 默认工具箱
+
+Transformers 提供了一个默认工具箱,用于增强智能体,您可以在初始化时通过 `add_base_tools=True` 参数将其添加到智能体中:
+
+- **文档问答**:给定一个文档(如图像格式的 PDF),回答关于该文档的问题([Donut](./model_doc/donut))
+- **图像问答**:给定一张图片,回答关于该图像的问题([VILT](./model_doc/vilt))
+- **语音转文本**:给定一个人讲述的音频录音,将其转录为文本(Whisper)
+- **文本转语音**:将文本转换为语音([SpeechT5](./model_doc/speecht5))
+- **翻译**:将给定的句子从源语言翻译为目标语言
+- **DuckDuckGo 搜索**:使用 `DuckDuckGo` 浏览器进行网络搜索
+- **Python 代码解释器**:在安全环境中运行 LLM 生成的 Python 代码。只有在初始化 [`ReactJsonAgent`] 时将 `add_base_tools=True` 时,代码智能体才会添加此工具,因为基于代码的智能体已经能够原生执行 Python 代码
+
+
+您可以通过调用 [`load_tool`] 函数来手动使用某个工具并执行任务。
+
+
+```python
+from transformers import load_tool
+
+tool = load_tool("text-to-speech")
+audio = tool("This is a text to speech tool")
+```
+
+
+### 创建新工具
+
+您可以为 `Hugging Face` 默认工具无法涵盖的用例创建自己的工具。
+例如,假设我们要创建一个返回在 `Hugging Face Hub` 上某个任务中下载次数最多的模型的工具。
+
+您将从以下代码开始:
+
+```python
+from huggingface_hub import list_models
+
+task = "text-classification"
+
+model = next(iter(list_models(filter=task, sort="downloads", direction=-1)))
+print(model.id)
+```
+
+这段代码可以很快转换为工具,只需将其包装成一个函数,并添加 `tool` 装饰器:
+
+
+```py
+from transformers import tool
+
+@tool
+def model_download_tool(task: str) -> str:
+ """
+ This is a tool that returns the most downloaded model of a given task on the Hugging Face Hub.
+ It returns the name of the checkpoint.
+
+ Args:
+ task: The task for which
+ """
+ model = next(iter(list_models(filter="text-classification", sort="downloads", direction=-1)))
+ return model.id
+```
+
+该函数需要:
+- 一个清晰的名称。名称通常描述工具的功能。由于代码返回某个任务中下载次数最多的模型,因此我们将其命名为 `model_download_tool`。
+- 对输入和输出进行类型提示
+- 描述,其中包括 "`Args`:" 部分,描述每个参数(这次不需要类型指示,它会从类型提示中获取)。
+
+所有这些将自动嵌入到智能体的系统提示中,因此请尽量使它们尽可能清晰!
+
+> [TIP]
+> 这个定义格式与 apply_chat_template 中使用的工具模式相同,唯一的区别是添加了 tool 装饰器:可以在我们的工具使用 API 中[了解更多](https://huggingface.co/blog/unified-tool-use#passing-tools-to-a-chat-template).
+
+然后,您可以直接初始化您的智能体:
+```py
+from transformers import CodeAgent
+agent = CodeAgent(tools=[model_download_tool], llm_engine=llm_engine)
+agent.run(
+ "Can you give me the name of the model that has the most downloads in the 'text-to-video' task on the Hugging Face Hub?"
+)
+```
+
+您将得到以下输出:
+```text
+======== New task ========
+Can you give me the name of the model that has the most downloads in the 'text-to-video' task on the Hugging Face Hub?
+==== Agent is executing the code below:
+most_downloaded_model = model_download_tool(task="text-to-video")
+print(f"The most downloaded model for the 'text-to-video' task is {most_downloaded_model}.")
+====
+```
+
+输出:
+`"The most downloaded model for the 'text-to-video' task is ByteDance/AnimateDiff-Lightning."`
+
+### 管理智能体的工具箱
+
+如果您已经初始化了一个智能体,但想添加一个新的工具,重新初始化智能体会很麻烦。借助 Transformers,您可以通过添加或替换工具来管理智能体的工具箱。
+
+让我们将 `model_download_tool` 添加到一个仅初始化了默认工具箱的现有智能体中。
+
+```python
+from transformers import CodeAgent
+
+agent = CodeAgent(tools=[], llm_engine=llm_engine, add_base_tools=True)
+agent.toolbox.add_tool(model_download_tool)
+```
+现在,我们可以同时使用新工具和之前的文本到语音工具:
+
+```python
+agent.run(
+ "Can you read out loud the name of the model that has the most downloads in the 'text-to-video' task on the Hugging Face Hub and return the audio?"
+)
+```
+
+
+| **Audio** |
+|------------------------------------------------------------------------------------------------------------------------------------------------------|
+|
+
+
+
+请记住,架构指的是模型的结构,而checkpoints是给定架构的权重。例如,[BERT](https://huggingface.co/google-bert/bert-base-uncased)是一种架构,而`google-bert/bert-base-uncased`是一个checkpoint。模型是一个通用术语,可以指代架构或checkpoint。
+
+
+
+
+在这个教程中,学习如何:
+
+* 加载预训练的分词器(`tokenizer`)
+* 加载预训练的图像处理器(`image processor`)
+* 加载预训练的特征提取器(`feature extractor`)
+* 加载预训练的处理器(`processor`)
+* 加载预训练的模型。
+
+
+## AutoTokenizer
+
+几乎所有的NLP任务都以`tokenizer`开始。`tokenizer`将您的输入转换为模型可以处理的格式。
+
+使用[`AutoTokenizer.from_pretrained`]加载`tokenizer`:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+```
+
+然后按照如下方式对输入进行分词:
+
+```py
+>>> sequence = "In a hole in the ground there lived a hobbit."
+>>> print(tokenizer(sequence))
+{'input_ids': [101, 1999, 1037, 4920, 1999, 1996, 2598, 2045, 2973, 1037, 7570, 10322, 4183, 1012, 102],
+ 'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+## AutoImageProcessor
+
+对于视觉任务,`image processor`将图像处理成正确的输入格式。
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+```
+
+
+## AutoFeatureExtractor
+
+对于音频任务,`feature extractor`将音频信号处理成正确的输入格式。
+
+使用[`AutoFeatureExtractor.from_pretrained`]加载`feature extractor`:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained(
+... "ehcalabres/wav2vec2-lg-xlsr-en-speech-emotion-recognition"
+... )
+```
+
+## AutoProcessor
+
+多模态任务需要一种`processor`,将两种类型的预处理工具结合起来。例如,[LayoutLMV2](model_doc/layoutlmv2)模型需要一个`image processor`来处理图像和一个`tokenizer`来处理文本;`processor`将两者结合起来。
+
+使用[`AutoProcessor.from_pretrained`]加载`processor`:
+
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("microsoft/layoutlmv2-base-uncased")
+```
+
+## AutoModel
+
+
+
+
+最后,`AutoModelFor`类让你可以加载给定任务的预训练模型(参见[这里](model_doc/auto)获取可用任务的完整列表)。例如,使用[`AutoModelForSequenceClassification.from_pretrained`]加载用于序列分类的模型:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+轻松地重复使用相同的checkpoint来为不同任务加载模型架构:
+
+
+```py
+>>> from transformers import AutoModelForTokenClassification
+
+>>> model = AutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+对于PyTorch模型,`from_pretrained()`方法使用`torch.load()`,它内部使用已知是不安全的`pickle`。一般来说,永远不要加载来自不可信来源或可能被篡改的模型。对于托管在Hugging Face Hub上的公共模型,这种安全风险在一定程度上得到了缓解,因为每次提交都会进行[恶意软件扫描](https://huggingface.co/docs/hub/security-malware)。请参阅[Hub文档](https://huggingface.co/docs/hub/security)以了解最佳实践,例如使用GPG进行[签名提交验证](https://huggingface.co/docs/hub/security-gpg#signing-commits-with-gpg)。
+
+TensorFlow和Flax的checkpoints不受影响,并且可以在PyTorch架构中使用`from_tf`和`from_flax`关键字参数,通过`from_pretrained`方法进行加载,来绕过此问题。
+
+
+
+一般来说,我们建议使用`AutoTokenizer`类和`AutoModelFor`类来加载预训练的模型实例。这样可以确保每次加载正确的架构。在下一个[教程](preprocessing)中,学习如何使用新加载的`tokenizer`, `image processor`, `feature extractor`和`processor`对数据集进行预处理以进行微调。
+
+
+
+最后,`TFAutoModelFor`类允许您加载给定任务的预训练模型(请参阅[这里](model_doc/auto)获取可用任务的完整列表)。例如,使用[`TFAutoModelForSequenceClassification.from_pretrained`]加载用于序列分类的模型:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+轻松地重复使用相同的checkpoint来为不同任务加载模型架构:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+一般来说,我们推荐使用`AutoTokenizer`类和`TFAutoModelFor`类来加载模型的预训练实例。这样可以确保每次加载正确的架构。在下一个[教程](preprocessing)中,学习如何使用新加载的`tokenizer`, `image processor`, `feature extractor`和`processor`对数据集进行预处理以进行微调。
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/benchmarks.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/benchmarks.md
new file mode 100644
index 0000000000000000000000000000000000000000..2e9787c9a3bb6bf2384ac2fb1eb5cd75c8379424
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/benchmarks.md
@@ -0,0 +1,377 @@
+
+
+# 基准测试
+
+
+
+小提示:Hugging Face的基准测试工具已经不再更新,建议使用外部基准测试库来衡量Transformer模
+型的速度和内存复杂度。
+
+
+
+[[open-in-colab]]
+
+让我们来看看如何对🤗 Transformers模型进行基准测试,以及进行测试的推荐策略和已有的基准测试结果。
+
+如果您需要更详细的回答,可以在[这里](https://github.com/huggingface/notebooks/tree/main/examples/benchmark.ipynb)找到更多关于基准测试的内容。
+
+
+## 如何对🤗 Transformers模型进行基准测试
+
+使用[`PyTorchBenchmark`]和[`TensorFlowBenchmark`]类可以灵活地对🤗 Transformers模型进行基准测试。这些基准测试类可以衡量模型在**推理**和**训练**过程中所需的**峰值内存**和**时间**。
+
+
+
+这里的**推理**指的是一次前向传播(forward pass),而训练则指一次前向传播和反向传播(backward pass)。
+
+
+
+
+基准测试类 [`PyTorchBenchmark`] 和 [`TensorFlowBenchmark`] 需要分别传入 [`PyTorchBenchmarkArguments`] 和 [`TensorFlowBenchmarkArguments`] 类型的对象来进行实例化。这些类是数据类型,包含了所有相关的配置参数,用于其对应的基准测试类。
+
+在下面的示例中,我们展示了如何对类型为 **bert-base-cased** 的BERT模型进行基准测试:
+
+
+
+```py
+>>> from transformers import PyTorchBenchmark, PyTorchBenchmarkArguments
+
+>>> args = PyTorchBenchmarkArguments(models=["google-bert/bert-base-uncased"], batch_sizes=[8], sequence_lengths=[8, 32, 128, 512])
+>>> benchmark = PyTorchBenchmark(args)
+```
+
+
+```py
+>>> from transformers import TensorFlowBenchmark, TensorFlowBenchmarkArguments
+
+>>> args = TensorFlowBenchmarkArguments(
+... models=["google-bert/bert-base-uncased"], batch_sizes=[8], sequence_lengths=[8, 32, 128, 512]
+... )
+>>> benchmark = TensorFlowBenchmark(args)
+```
+
+
+
+在这里,基准测试的参数数据类接受了三个主要的参数,即 `models`、`batch_sizes` 和`sequence_lengths`。其中,`models` 是必需的参数,它期望一个来自[模型库](https://huggingface.co/models)的模型标识符列表。`batch_sizes` 和 `sequence_lengths` 是列表类型的参数,定义了进行基准测试时 `input_ids` 的批量大小和序列长度。
+
+这些是基准测试数据类中可以配置的一些主要参数。除此之外,基准测试数据类中还可以配置很多其他参数。如需要查看更详细的配置参数,可以直接查看以下文件:
+
+* `src/transformers/benchmark/benchmark_args_utils.py`
+* `src/transformers/benchmark/benchmark_args.py`(针对 PyTorch)
+* `src/transformers/benchmark/benchmark_args_tf.py`(针对 TensorFlow)
+
+另外,您还可以通过在根目录下运行以下命令,查看针对 PyTorch 和 TensorFlow 的所有可配置参数的描述列表:
+``` bash python examples/pytorch/benchmarking/run_benchmark.py --help ```
+这些命令将列出所有可以配置的参数,它们可以帮助您更加灵活地进行基准测试。
+
+
+
+
+
+
+以下代码通过`PyTorchBenchmarkArguments`设置模型批处理大小和序列长度,然后调用`benchmark.run()`执行基准测试。
+
+```py
+>>> results = benchmark.run()
+>>> print(results)
+==================== INFERENCE - SPEED - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Time in s
+--------------------------------------------------------------------------------
+google-bert/bert-base-uncased 8 8 0.006
+google-bert/bert-base-uncased 8 32 0.006
+google-bert/bert-base-uncased 8 128 0.018
+google-bert/bert-base-uncased 8 512 0.088
+--------------------------------------------------------------------------------
+
+==================== INFERENCE - MEMORY - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Memory in MB
+--------------------------------------------------------------------------------
+google-bert/bert-base-uncased 8 8 1227
+google-bert/bert-base-uncased 8 32 1281
+google-bert/bert-base-uncased 8 128 1307
+google-bert/bert-base-uncased 8 512 1539
+--------------------------------------------------------------------------------
+
+==================== ENVIRONMENT INFORMATION ====================
+
+- transformers_version: 2.11.0
+- framework: PyTorch
+- use_torchscript: False
+- framework_version: 1.4.0
+- python_version: 3.6.10
+- system: Linux
+- cpu: x86_64
+- architecture: 64bit
+- date: 2020-06-29
+- time: 08:58:43.371351
+- fp16: False
+- use_multiprocessing: True
+- only_pretrain_model: False
+- cpu_ram_mb: 32088
+- use_gpu: True
+- num_gpus: 1
+- gpu: TITAN RTX
+- gpu_ram_mb: 24217
+- gpu_power_watts: 280.0
+- gpu_performance_state: 2
+- use_tpu: False
+```
+
+
+```bash
+python examples/tensorflow/benchmarking/run_benchmark_tf.py --help
+```
+
+接下来,只需要调用 `benchmark.run()` 就能轻松运行已经实例化的基准测试对象。
+
+```py
+>>> results = benchmark.run()
+>>> print(results)
+>>> results = benchmark.run()
+>>> print(results)
+==================== INFERENCE - SPEED - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Time in s
+--------------------------------------------------------------------------------
+google-bert/bert-base-uncased 8 8 0.005
+google-bert/bert-base-uncased 8 32 0.008
+google-bert/bert-base-uncased 8 128 0.022
+google-bert/bert-base-uncased 8 512 0.105
+--------------------------------------------------------------------------------
+
+==================== INFERENCE - MEMORY - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Memory in MB
+--------------------------------------------------------------------------------
+google-bert/bert-base-uncased 8 8 1330
+google-bert/bert-base-uncased 8 32 1330
+google-bert/bert-base-uncased 8 128 1330
+google-bert/bert-base-uncased 8 512 1770
+--------------------------------------------------------------------------------
+
+==================== ENVIRONMENT INFORMATION ====================
+
+- transformers_version: 2.11.0
+- framework: Tensorflow
+- use_xla: False
+- framework_version: 2.2.0
+- python_version: 3.6.10
+- system: Linux
+- cpu: x86_64
+- architecture: 64bit
+- date: 2020-06-29
+- time: 09:26:35.617317
+- fp16: False
+- use_multiprocessing: True
+- only_pretrain_model: False
+- cpu_ram_mb: 32088
+- use_gpu: True
+- num_gpus: 1
+- gpu: TITAN RTX
+- gpu_ram_mb: 24217
+- gpu_power_watts: 280.0
+- gpu_performance_state: 2
+- use_tpu: False
+```
+
+
+
+
+
+在一般情况下,基准测试会测量推理(inference)的**时间**和**所需内存**。在上面的示例输出中,前两部分显示了与**推理时间**和**推理内存**对应的结果。与此同时,关于计算环境的所有相关信息(例如 GPU 类型、系统、库版本等)会在第三部分的**环境信息**中打印出来。你可以通过在 [`PyTorchBenchmarkArguments`] 和 [`TensorFlowBenchmarkArguments`] 中添加 `save_to_csv=True`参数,将这些信息保存到一个 .csv 文件中。在这种情况下,每一部分的信息会分别保存在不同的 .csv 文件中。每个 .csv 文件的路径也可以通过参数数据类进行定义。
+
+
+您可以选择不通过预训练模型的模型标识符(如 `google-bert/bert-base-uncased`)进行基准测试,而是对任何可用模型类的任意配置进行基准测试。在这种情况下,我们必须将一系列配置与基准测试参数一起传入,方法如下:
+
+
+
+```py
+>>> from transformers import PyTorchBenchmark, PyTorchBenchmarkArguments, BertConfig
+
+>>> args = PyTorchBenchmarkArguments(
+... models=["bert-base", "bert-384-hid", "bert-6-lay"], batch_sizes=[8], sequence_lengths=[8, 32, 128, 512]
+... )
+>>> config_base = BertConfig()
+>>> config_384_hid = BertConfig(hidden_size=384)
+>>> config_6_lay = BertConfig(num_hidden_layers=6)
+
+>>> benchmark = PyTorchBenchmark(args, configs=[config_base, config_384_hid, config_6_lay])
+>>> benchmark.run()
+==================== INFERENCE - SPEED - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Time in s
+--------------------------------------------------------------------------------
+bert-base 8 128 0.006
+bert-base 8 512 0.006
+bert-base 8 128 0.018
+bert-base 8 512 0.088
+bert-384-hid 8 8 0.006
+bert-384-hid 8 32 0.006
+bert-384-hid 8 128 0.011
+bert-384-hid 8 512 0.054
+bert-6-lay 8 8 0.003
+bert-6-lay 8 32 0.004
+bert-6-lay 8 128 0.009
+bert-6-lay 8 512 0.044
+--------------------------------------------------------------------------------
+
+==================== INFERENCE - MEMORY - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Memory in MB
+--------------------------------------------------------------------------------
+bert-base 8 8 1277
+bert-base 8 32 1281
+bert-base 8 128 1307
+bert-base 8 512 1539
+bert-384-hid 8 8 1005
+bert-384-hid 8 32 1027
+bert-384-hid 8 128 1035
+bert-384-hid 8 512 1255
+bert-6-lay 8 8 1097
+bert-6-lay 8 32 1101
+bert-6-lay 8 128 1127
+bert-6-lay 8 512 1359
+--------------------------------------------------------------------------------
+
+==================== ENVIRONMENT INFORMATION ====================
+
+- transformers_version: 2.11.0
+- framework: PyTorch
+- use_torchscript: False
+- framework_version: 1.4.0
+- python_version: 3.6.10
+- system: Linux
+- cpu: x86_64
+- architecture: 64bit
+- date: 2020-06-29
+- time: 09:35:25.143267
+- fp16: False
+- use_multiprocessing: True
+- only_pretrain_model: False
+- cpu_ram_mb: 32088
+- use_gpu: True
+- num_gpus: 1
+- gpu: TITAN RTX
+- gpu_ram_mb: 24217
+- gpu_power_watts: 280.0
+- gpu_performance_state: 2
+- use_tpu: False
+```
+
+
+```py
+>>> from transformers import TensorFlowBenchmark, TensorFlowBenchmarkArguments, BertConfig
+
+>>> args = TensorFlowBenchmarkArguments(
+... models=["bert-base", "bert-384-hid", "bert-6-lay"], batch_sizes=[8], sequence_lengths=[8, 32, 128, 512]
+... )
+>>> config_base = BertConfig()
+>>> config_384_hid = BertConfig(hidden_size=384)
+>>> config_6_lay = BertConfig(num_hidden_layers=6)
+
+>>> benchmark = TensorFlowBenchmark(args, configs=[config_base, config_384_hid, config_6_lay])
+>>> benchmark.run()
+==================== INFERENCE - SPEED - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Time in s
+--------------------------------------------------------------------------------
+bert-base 8 8 0.005
+bert-base 8 32 0.008
+bert-base 8 128 0.022
+bert-base 8 512 0.106
+bert-384-hid 8 8 0.005
+bert-384-hid 8 32 0.007
+bert-384-hid 8 128 0.018
+bert-384-hid 8 512 0.064
+bert-6-lay 8 8 0.002
+bert-6-lay 8 32 0.003
+bert-6-lay 8 128 0.0011
+bert-6-lay 8 512 0.074
+--------------------------------------------------------------------------------
+
+==================== INFERENCE - MEMORY - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Memory in MB
+--------------------------------------------------------------------------------
+bert-base 8 8 1330
+bert-base 8 32 1330
+bert-base 8 128 1330
+bert-base 8 512 1770
+bert-384-hid 8 8 1330
+bert-384-hid 8 32 1330
+bert-384-hid 8 128 1330
+bert-384-hid 8 512 1540
+bert-6-lay 8 8 1330
+bert-6-lay 8 32 1330
+bert-6-lay 8 128 1330
+bert-6-lay 8 512 1540
+--------------------------------------------------------------------------------
+
+==================== ENVIRONMENT INFORMATION ====================
+
+- transformers_version: 2.11.0
+- framework: Tensorflow
+- use_xla: False
+- framework_version: 2.2.0
+- python_version: 3.6.10
+- system: Linux
+- cpu: x86_64
+- architecture: 64bit
+- date: 2020-06-29
+- time: 09:38:15.487125
+- fp16: False
+- use_multiprocessing: True
+- only_pretrain_model: False
+- cpu_ram_mb: 32088
+- use_gpu: True
+- num_gpus: 1
+- gpu: TITAN RTX
+- gpu_ram_mb: 24217
+- gpu_power_watts: 280.0
+- gpu_performance_state: 2
+- use_tpu: False
+```
+
+
+
+
+ **推理时间**和**推理所需内存**会被重新测量,不过这次是针对 `BertModel` 类的自定义配置进行基准测试。这个功能在决定模型应该使用哪种配置进行训练时尤其有用。
+
+
+## 基准测试的推荐策略
+本节列出了一些在对模型进行基准测试时比较推荐的策略:
+
+* 目前,该模块只支持单设备基准测试。在进行 GPU 基准测试时,建议用户通过设置 `CUDA_VISIBLE_DEVICES` 环境变量来指定代码应在哪个设备上运行,例如在运行代码前执行 `export CUDA_VISIBLE_DEVICES=0`。
+* `no_multi_processing` 选项仅应在测试和调试时设置为 `True`。为了确保内存测量的准确性,建议将每个内存基准测试单独运行在一个进程中,并确保 `no_multi_processing` 设置为 `True`。
+* 当您分享模型基准测试结果时,应始终提供环境信息。由于 GPU 设备、库版本等之间可能存在较大差异,单独的基准测试结果对社区的帮助有限。
+
+
+## 分享您的基准测试结果
+
+先前的所有可用的核心模型(当时有10个)都已针对 **推理时间** 进行基准测试,涵盖了多种不同的设置:使用 PyTorch(包不包含 TorchScript),使用 TensorFlow(包不包含 XLA)。所有的测试都在 CPU(除了 TensorFlow XLA)和 GPU 上进行。
+
+这种方法的详细信息可以在 [这篇博客](https://medium.com/huggingface/benchmarking-transformers-pytorch-and-tensorflow-e2917fb891c2) 中找到,测试结果可以在 [这里](https://docs.google.com/spreadsheets/d/1sryqufw2D0XlUH4sq3e9Wnxu5EAQkaohzrJbd5HdQ_w/edit?usp=sharing) 查看。
+
+
+您可以借助新的 **基准测试** 工具比以往任何时候都更容易地分享您的基准测试结果!
+
+- [PyTorch 基准测试结果](https://github.com/huggingface/transformers/tree/main/examples/pytorch/benchmarking/README.md)
+- [TensorFlow 基准测试结果](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/benchmarking/README.md)
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/bertology.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/bertology.md
new file mode 100644
index 0000000000000000000000000000000000000000..9b39f948339474ea730527c2f4829cf13cb24314
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/bertology.md
@@ -0,0 +1,33 @@
+
+
+# 基于BERT进行的相关研究(BERTology)
+
+当前,一个新兴的研究领域正致力于探索大规模 transformer 模型(如BERT)的内部工作机制,一些人称之为“BERTology”。以下是这个领域的一些典型示例:
+
+
+- BERT Rediscovers the Classical NLP Pipeline by Ian Tenney, Dipanjan Das, Ellie Pavlick:
+ https://arxiv.org/abs/1905.05950
+- Are Sixteen Heads Really Better than One? by Paul Michel, Omer Levy, Graham Neubig: https://arxiv.org/abs/1905.10650
+- What Does BERT Look At? An Analysis of BERT's Attention by Kevin Clark, Urvashi Khandelwal, Omer Levy, Christopher D.
+ Manning: https://arxiv.org/abs/1906.04341
+- CAT-probing: A Metric-based Approach to Interpret How Pre-trained Models for Programming Language Attend Code Structure: https://arxiv.org/abs/2210.04633
+
+
+为了助力这一新兴领域的发展,我们在BERT/GPT/GPT-2模型中增加了一些附加功能,方便人们访问其内部表示,这些功能主要借鉴了Paul Michel的杰出工作(https://arxiv.org/abs/1905.10650):
+
+
+- 访问BERT/GPT/GPT-2的所有隐藏状态,
+- 访问BERT/GPT/GPT-2每个注意力头的所有注意力权重,
+- 检索注意力头的输出值和梯度,以便计算头的重要性得分并对头进行剪枝,详情可见论文:https://arxiv.org/abs/1905.10650。
+
+为了帮助您理解和使用这些功能,我们添加了一个具体的示例脚本:[bertology.py](https://github.com/huggingface/transformers/tree/main/examples/research_projects/bertology/run_bertology.py),该脚本可以对一个在 GLUE 数据集上预训练的模型进行信息提取与剪枝。
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/big_models.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/big_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..2215c7066182065b080b63580ad28b1414758abf
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/big_models.md
@@ -0,0 +1,123 @@
+
+
+# 实例化大型模型
+
+当你想使用一个非常大的预训练模型时,一个挑战是尽量减少对内存的使用。通常从PyTorch开始的工作流程如下:
+
+1. 用随机权重创建你的模型。
+2. 加载你的预训练权重。
+3. 将这些预训练权重放入你的随机模型中。
+
+步骤1和2都需要完整版本的模型在内存中,这在大多数情况下不是问题,但如果你的模型开始达到几个GB的大小,这两个副本可能会让你超出内存的限制。更糟糕的是,如果你使用`torch.distributed`来启动分布式训练,每个进程都会加载预训练模型并将这两个副本存储在内存中。
+
+
+
+请注意,随机创建的模型使用“空”张量进行初始化,这些张量占用内存空间但不填充它(因此随机值是给定时间内该内存块中的任何内容)。在第3步之后,对未初始化的权重执行适合模型/参数种类的随机初始化(例如正态分布),以尽可能提高速度!
+
+
+
+在本指南中,我们将探讨 Transformers 提供的解决方案来处理这个问题。请注意,这是一个积极开发的领域,因此这里解释的API在将来可能会略有变化。
+
+## 分片checkpoints
+
+自4.18.0版本起,占用空间超过10GB的模型检查点将自动分成较小的片段。在使用`model.save_pretrained(save_dir)`时,您最终会得到几个部分`checkpoints`(每个的大小都小于10GB)以及一个索引,该索引将参数名称映射到存储它们的文件。
+
+您可以使用`max_shard_size`参数来控制分片之前的最大大小。为了示例的目的,我们将使用具有较小分片大小的普通大小的模型:让我们以传统的BERT模型为例。
+
+
+```py
+from transformers import AutoModel
+
+model = AutoModel.from_pretrained("google-bert/bert-base-cased")
+```
+
+如果您使用 [`PreTrainedModel.save_pretrained`](模型预训练保存) 进行保存,您将得到一个新的文件夹,其中包含两个文件:模型的配置和权重:
+
+```py
+>>> import os
+>>> import tempfile
+
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir)
+... print(sorted(os.listdir(tmp_dir)))
+['config.json', 'pytorch_model.bin']
+```
+
+现在让我们使用最大分片大小为200MB:
+
+```py
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... print(sorted(os.listdir(tmp_dir)))
+['config.json', 'pytorch_model-00001-of-00003.bin', 'pytorch_model-00002-of-00003.bin', 'pytorch_model-00003-of-00003.bin', 'pytorch_model.bin.index.json']
+```
+
+在模型配置文件最上方,我们可以看到三个不同的权重文件,以及一个`index.json`索引文件。这样的`checkpoint`可以使用[`~PreTrainedModel.from_pretrained`]方法完全重新加载:
+
+```py
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... new_model = AutoModel.from_pretrained(tmp_dir)
+```
+
+对于大型模型来说,这样做的主要优点是在上述工作流程的步骤2中,每个`checkpoint`的分片在前一个分片之后加载,从而将内存中的内存使用限制在模型大小加上最大分片的大小。
+
+在后台,索引文件用于确定`checkpoint`中包含哪些键以及相应的权重存储在哪里。我们可以像加载任何json一样加载该索引,并获得一个字典:
+
+```py
+>>> import json
+
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... with open(os.path.join(tmp_dir, "pytorch_model.bin.index.json"), "r") as f:
+... index = json.load(f)
+
+>>> print(index.keys())
+dict_keys(['metadata', 'weight_map'])
+```
+
+目前元数据仅包括模型的总大小。我们计划在将来添加其他信息:
+```py
+>>> index["metadata"]
+{'total_size': 433245184}
+```
+
+权重映射是该索引的主要部分,它将每个参数的名称(通常在PyTorch模型的`state_dict`中找到)映射到存储该参数的文件:
+
+```py
+>>> index["weight_map"]
+{'embeddings.LayerNorm.bias': 'pytorch_model-00001-of-00003.bin',
+ 'embeddings.LayerNorm.weight': 'pytorch_model-00001-of-00003.bin',
+ ...
+```
+
+如果您想直接在模型内部加载这样的分片`checkpoint`,而不使用 [`PreTrainedModel.from_pretrained`](就像您会为完整`checkpoint`执行 `model.load_state_dict()` 一样),您应该使用 [`modeling_utils.load_sharded_checkpoint`]:
+
+
+```py
+>>> from transformers.modeling_utils import load_sharded_checkpoint
+
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... load_sharded_checkpoint(model, tmp_dir)
+```
+
+## 低内存加载
+
+分片`checkpoints`在上述工作流的第2步中降低了内存使用,但为了在低内存环境中使用该模型,我们建议使用基于 Accelerate 库的工具。
+
+请阅读以下指南以获取更多信息:[使用 Accelerate 进行大模型加载](./main_classes/model#large-model-loading)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/chat_templating.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/chat_templating.md
new file mode 100644
index 0000000000000000000000000000000000000000..e0ab50b634c7805cb135a986bacd2b30665d8b97
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/chat_templating.md
@@ -0,0 +1,434 @@
+
+
+# 聊天模型的模板
+
+## 介绍
+
+LLM 的一个常见应用场景是聊天。在聊天上下文中,不再是连续的文本字符串构成的语句(不同于标准的语言模型),
+聊天模型由一条或多条消息组成的对话组成,每条消息都有一个“用户”或“助手”等 **角色**,还包括消息文本。
+
+与`Tokenizer`类似,不同的模型对聊天的输入格式要求也不同。这就是我们添加**聊天模板**作为一个功能的原因。
+聊天模板是`Tokenizer`的一部分。用来把问答的对话内容转换为模型的输入`prompt`。
+
+
+让我们通过一个快速的示例来具体说明,使用`BlenderBot`模型。
+BlenderBot有一个非常简单的默认模板,主要是在对话轮之间添加空格:
+
+```python
+>>> from transformers import AutoTokenizer
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/blenderbot-400M-distill")
+
+>>> chat = [
+... {"role": "user", "content": "Hello, how are you?"},
+... {"role": "assistant", "content": "I'm doing great. How can I help you today?"},
+... {"role": "user", "content": "I'd like to show off how chat templating works!"},
+... ]
+
+>>> tokenizer.apply_chat_template(chat, tokenize=False)
+" Hello, how are you? I'm doing great. How can I help you today? I'd like to show off how chat templating works!"
+```
+
+注意,整个聊天对话内容被压缩成了一整个字符串。如果我们使用默认设置的`tokenize=True`,那么该字符串也将被tokenized处理。
+不过,为了看到更复杂的模板实际运行,让我们使用`mistralai/Mistral-7B-Instruct-v0.1`模型。
+
+```python
+>>> from transformers import AutoTokenizer
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-Instruct-v0.1")
+
+>>> chat = [
+... {"role": "user", "content": "Hello, how are you?"},
+... {"role": "assistant", "content": "I'm doing great. How can I help you today?"},
+... {"role": "user", "content": "I'd like to show off how chat templating works!"},
+... ]
+
+>>> tokenizer.apply_chat_template(chat, tokenize=False)
+"[INST] Hello, how are you? [/INST]I'm doing great. How can I help you today? [INST] I'd like to show off how chat templating works! [/INST]"
+```
+
+可以看到,这一次tokenizer已经添加了[INST]和[/INST]来表示用户消息的开始和结束。
+Mistral-instruct是有使用这些token进行训练的,但BlenderBot没有。
+
+## 我如何使用聊天模板?
+
+正如您在上面的示例中所看到的,聊天模板非常容易使用。只需构建一系列带有`role`和`content`键的消息,
+然后将其传递给[`~PreTrainedTokenizer.apply_chat_template`]方法。
+另外,在将聊天模板用作模型预测的输入时,还建议使用`add_generation_prompt=True`来添加[generation prompt](#什么是generation-prompts)。
+
+这是一个准备`model.generate()`的示例,使用`Zephyr`模型:
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+checkpoint = "HuggingFaceH4/zephyr-7b-beta"
+tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+model = AutoModelForCausalLM.from_pretrained(checkpoint) # You may want to use bfloat16 and/or move to GPU here
+
+messages = [
+ {
+ "role": "system",
+ "content": "You are a friendly chatbot who always responds in the style of a pirate",
+ },
+ {"role": "user", "content": "How many helicopters can a human eat in one sitting?"},
+ ]
+tokenized_chat = tokenizer.apply_chat_template(messages, tokenize=True, add_generation_prompt=True, return_tensors="pt")
+print(tokenizer.decode(tokenized_chat[0]))
+```
+这将生成Zephyr期望的输入格式的字符串。它看起来像这样:
+```text
+<|system|>
+You are a friendly chatbot who always responds in the style of a pirate
+<|user|>
+How many helicopters can a human eat in one sitting?
+<|assistant|>
+```
+
+现在我们已经按照`Zephyr`的要求传入prompt了,我们可以使用模型来生成对用户问题的回复:
+
+```python
+outputs = model.generate(tokenized_chat, max_new_tokens=128)
+print(tokenizer.decode(outputs[0]))
+```
+
+输出结果是:
+
+```text
+<|system|>
+You are a friendly chatbot who always responds in the style of a pirate
+<|user|>
+How many helicopters can a human eat in one sitting?
+<|assistant|>
+Matey, I'm afraid I must inform ye that humans cannot eat helicopters. Helicopters are not food, they are flying machines. Food is meant to be eaten, like a hearty plate o' grog, a savory bowl o' stew, or a delicious loaf o' bread. But helicopters, they be for transportin' and movin' around, not for eatin'. So, I'd say none, me hearties. None at all.
+```
+啊,原来这么容易!
+
+## 有自动化的聊天`pipeline`吗?
+
+有的,[`TextGenerationPipeline`]。这个`pipeline`的设计是为了方便使用聊天模型。让我们再试一次 Zephyr 的例子,但这次使用`pipeline`:
+
+```python
+from transformers import pipeline
+
+pipe = pipeline("text-generation", "HuggingFaceH4/zephyr-7b-beta")
+messages = [
+ {
+ "role": "system",
+ "content": "You are a friendly chatbot who always responds in the style of a pirate",
+ },
+ {"role": "user", "content": "How many helicopters can a human eat in one sitting?"},
+]
+print(pipe(messages, max_new_tokens=256)['generated_text'][-1])
+```
+
+```text
+{'role': 'assistant', 'content': "Matey, I'm afraid I must inform ye that humans cannot eat helicopters. Helicopters are not food, they are flying machines. Food is meant to be eaten, like a hearty plate o' grog, a savory bowl o' stew, or a delicious loaf o' bread. But helicopters, they be for transportin' and movin' around, not for eatin'. So, I'd say none, me hearties. None at all."}
+```
+
+[`TextGenerationPipeline`]将负责处理所有的`tokenized`并调用`apply_chat_template`,一旦模型有了聊天模板,您只需要初始化pipeline并传递消息列表!
+
+## 什么是"generation prompts"?
+
+您可能已经注意到`apply_chat_template`方法有一个`add_generation_prompt`参数。
+这个参数告诉模板添加模型开始答复的标记。例如,考虑以下对话:
+
+```python
+messages = [
+ {"role": "user", "content": "Hi there!"},
+ {"role": "assistant", "content": "Nice to meet you!"},
+ {"role": "user", "content": "Can I ask a question?"}
+]
+```
+
+这是`add_generation_prompt=False`的结果,使用ChatML模板:
+```python
+tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=False)
+"""<|im_start|>user
+Hi there!<|im_end|>
+<|im_start|>assistant
+Nice to meet you!<|im_end|>
+<|im_start|>user
+Can I ask a question?<|im_end|>
+"""
+```
+
+下面这是`add_generation_prompt=True`的结果:
+
+```python
+tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
+"""<|im_start|>user
+Hi there!<|im_end|>
+<|im_start|>assistant
+Nice to meet you!<|im_end|>
+<|im_start|>user
+Can I ask a question?<|im_end|>
+<|im_start|>assistant
+"""
+```
+
+这一次我们添加了模型开始答复的标记。这可以确保模型生成文本时只会给出答复,而不会做出意外的行为,比如继续用户的消息。
+记住,聊天模型只是语言模型,它们被训练来继续文本,而聊天对它们来说只是一种特殊的文本!
+你需要用适当的控制标记来引导它们,让它们知道自己应该做什么。
+
+并非所有模型都需要生成提示。一些模型,如BlenderBot和LLaMA,在模型回复之前没有任何特殊标记。
+在这些情况下,`add_generation_prompt`参数将不起作用。`add_generation_prompt`参数取决于你所使用的模板。
+
+## 我可以在训练中使用聊天模板吗?
+
+可以!我们建议您将聊天模板应用为数据集的预处理步骤。之后,您可以像进行任何其他语言模型训练任务一样继续。
+在训练时,通常应该设置`add_generation_prompt=False`,因为添加的助手标记在训练过程中并不会有帮助。
+让我们看一个例子:
+
+```python
+from transformers import AutoTokenizer
+from datasets import Dataset
+
+tokenizer = AutoTokenizer.from_pretrained("HuggingFaceH4/zephyr-7b-beta")
+
+chat1 = [
+ {"role": "user", "content": "Which is bigger, the moon or the sun?"},
+ {"role": "assistant", "content": "The sun."}
+]
+chat2 = [
+ {"role": "user", "content": "Which is bigger, a virus or a bacterium?"},
+ {"role": "assistant", "content": "A bacterium."}
+]
+
+dataset = Dataset.from_dict({"chat": [chat1, chat2]})
+dataset = dataset.map(lambda x: {"formatted_chat": tokenizer.apply_chat_template(x["chat"], tokenize=False, add_generation_prompt=False)})
+print(dataset['formatted_chat'][0])
+```
+结果是:
+```text
+<|user|>
+Which is bigger, the moon or the sun?
+<|assistant|>
+The sun.
+```
+
+这样,后面你可以使用`formatted_chat`列,跟标准语言建模任务中一样训练即可。
+## 高级:聊天模板是如何工作的?
+
+模型的聊天模板存储在`tokenizer.chat_template`属性上。如果没有设置,则将使用该模型的默认模板。
+让我们来看看`BlenderBot`的模板:
+```python
+
+>>> from transformers import AutoTokenizer
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/blenderbot-400M-distill")
+
+>>> tokenizer.chat_template
+"{% for message in messages %}{% if message['role'] == 'user' %}{{ ' ' }}{% endif %}{{ message['content'] }}{% if not loop.last %}{{ ' ' }}{% endif %}{% endfor %}{{ eos_token }}"
+```
+
+这看着有点复杂。让我们添加一些换行和缩进,使其更易读。
+请注意,默认情况下忽略每个块后的第一个换行以及块之前的任何前导空格,
+使用Jinja的`trim_blocks`和`lstrip_blocks`标签。
+这里,请注意空格的使用。我们强烈建议您仔细检查模板是否打印了多余的空格!
+```
+{% for message in messages %}
+ {% if message['role'] == 'user' %}
+ {{ ' ' }}
+ {% endif %}
+ {{ message['content'] }}
+ {% if not loop.last %}
+ {{ ' ' }}
+ {% endif %}
+{% endfor %}
+{{ eos_token }}
+```
+
+如果你之前不了解[Jinja template](https://jinja.palletsprojects.com/en/3.1.x/templates/)。
+Jinja是一种模板语言,允许你编写简单的代码来生成文本。
+在许多方面,代码和语法类似于Python。在纯Python中,这个模板看起来会像这样:
+```python
+for idx, message in enumerate(messages):
+ if message['role'] == 'user':
+ print(' ')
+ print(message['content'])
+ if not idx == len(messages) - 1: # Check for the last message in the conversation
+ print(' ')
+print(eos_token)
+```
+
+这里使用Jinja模板处理如下三步:
+1. 对于每条消息,如果消息是用户消息,则在其前面添加一个空格,否则不打印任何内容
+2. 添加消息内容
+3. 如果消息不是最后一条,请在其后添加两个空格。在最后一条消息之后,打印`EOS`。
+
+这是一个简单的模板,它不添加任何控制tokens,也不支持`system`消息(常用于指导模型在后续对话中如何表现)。
+但 Jinja 给了你很大的灵活性来做这些事情!让我们看一个 Jinja 模板,
+它可以实现类似于LLaMA的prompt输入(请注意,真正的LLaMA模板包括`system`消息,请不要在实际代码中使用这个简单模板!)
+```
+{% for message in messages %}
+ {% if message['role'] == 'user' %}
+ {{ bos_token + '[INST] ' + message['content'] + ' [/INST]' }}
+ {% elif message['role'] == 'system' %}
+ {{ '<>\\n' + message['content'] + '\\n< >\\n\\n' }}
+ {% elif message['role'] == 'assistant' %}
+ {{ ' ' + message['content'] + ' ' + eos_token }}
+ {% endif %}
+{% endfor %}
+```
+
+这里稍微看一下,就能明白这个模板的作用:它根据每条消息的“角色”添加对应的消息。
+`user`、`assistant`、`system`的消息需要分别处理,因为它们代表不同的角色输入。
+
+## 高级:编辑聊天模板
+
+### 如何创建聊天模板?
+
+很简单,你只需编写一个jinja模板并设置`tokenizer.chat_template`。你也可以从一个现有模板开始,只需要简单编辑便可以!
+例如,我们可以采用上面的LLaMA模板,并在助手消息中添加"[ASST]"和"[/ASST]":
+```
+{% for message in messages %}
+ {% if message['role'] == 'user' %}
+ {{ bos_token + '[INST] ' + message['content'].strip() + ' [/INST]' }}
+ {% elif message['role'] == 'system' %}
+ {{ '<>\\n' + message['content'].strip() + '\\n< >\\n\\n' }}
+ {% elif message['role'] == 'assistant' %}
+ {{ '[ASST] ' + message['content'] + ' [/ASST]' + eos_token }}
+ {% endif %}
+{% endfor %}
+```
+
+现在,只需设置`tokenizer.chat_template`属性。下次使用[`~PreTrainedTokenizer.apply_chat_template`]时,它将使用您的新模板!
+此属性将保存在`tokenizer_config.json`文件中,因此您可以使用[`~utils.PushToHubMixin.push_to_hub`]将新模板上传到 Hub,
+这样每个人都可以使用你模型的模板!
+
+```python
+template = tokenizer.chat_template
+template = template.replace("SYS", "SYSTEM") # Change the system token
+tokenizer.chat_template = template # Set the new template
+tokenizer.push_to_hub("model_name") # Upload your new template to the Hub!
+```
+
+由于[`~PreTrainedTokenizer.apply_chat_template`]方法是由[`TextGenerationPipeline`]类调用,
+因此一旦你设置了聊天模板,您的模型将自动与[`TextGenerationPipeline`]兼容。
+### “默认”模板是什么?
+
+在引入聊天模板(chat_template)之前,聊天prompt是在模型中通过硬编码处理的。为了向前兼容,我们保留了这种硬编码处理聊天prompt的方法。
+如果一个模型没有设置聊天模板,但其模型有默认模板,`TextGenerationPipeline`类和`apply_chat_template`等方法将使用该模型的聊天模板。
+您可以通过检查`tokenizer.default_chat_template`属性来查找`tokenizer`的默认模板。
+
+这是我们纯粹为了向前兼容性而做的事情,以避免破坏任何现有的工作流程。即使默认的聊天模板适用于您的模型,
+我们强烈建议通过显式设置`chat_template`属性来覆盖默认模板,以便向用户清楚地表明您的模型已经正确的配置了聊天模板,
+并且为了未来防范默认模板被修改或弃用的情况。
+### 我应该使用哪个模板?
+
+在为已经训练过的聊天模型设置模板时,您应确保模板与模型在训练期间看到的消息格式完全匹配,否则可能会导致性能下降。
+即使您继续对模型进行训练,也应保持聊天模板不变,这样可能会获得最佳性能。
+这与`tokenization`非常类似,在推断时,你选用跟训练时一样的`tokenization`,通常会获得最佳性能。
+
+如果您从头开始训练模型,或者在微调基础语言模型进行聊天时,您有很大的自由选择适当的模板!
+LLMs足够聪明,可以学会处理许多不同的输入格式。我们为没有特定类别模板的模型提供一个默认模板,该模板遵循
+`ChatML` format格式要求,对于许多用例来说,
+这是一个很好的、灵活的选择。
+
+默认模板看起来像这样:
+
+```
+{% for message in messages %}
+ {{'<|im_start|>' + message['role'] + '\n' + message['content'] + '<|im_end|>' + '\n'}}
+{% endfor %}
+```
+
+
+如果您喜欢这个模板,下面是一行代码的模板形式,它可以直接复制到您的代码中。这一行代码还包括了[generation prompts](#什么是"generation prompts"?),
+但请注意它不会添加`BOS`或`EOS`token。
+如果您的模型需要这些token,它们不会被`apply_chat_template`自动添加,换句话说,文本的默认处理参数是`add_special_tokens=False`。
+这是为了避免模板和`add_special_tokens`逻辑产生冲突,如果您的模型需要特殊tokens,请确保将它们添加到模板中!
+
+```
+tokenizer.chat_template = "{% if not add_generation_prompt is defined %}{% set add_generation_prompt = false %}{% endif %}{% for message in messages %}{{'<|im_start|>' + message['role'] + '\n' + message['content'] + '<|im_end|>' + '\n'}}{% endfor %}{% if add_generation_prompt %}{{ '<|im_start|>assistant\n' }}{% endif %}"
+```
+
+该模板将每条消息包装在`<|im_start|>`和`<|im_end|>`tokens里面,并将角色简单地写为字符串,这样可以灵活地训练角色。输出如下:
+```text
+<|im_start|>system
+You are a helpful chatbot that will do its best not to say anything so stupid that people tweet about it.<|im_end|>
+<|im_start|>user
+How are you?<|im_end|>
+<|im_start|>assistant
+I'm doing great!<|im_end|>
+```
+
+`user`,`system`和`assistant`是对话助手模型的标准角色,如果您的模型要与[`TextGenerationPipeline`]兼容,我们建议你使用这些角色。
+但您可以不局限于这些角色,模板非常灵活,任何字符串都可以成为角色。
+
+### 如何添加聊天模板?
+
+如果您有任何聊天模型,您应该设置它们的`tokenizer.chat_template`属性,并使用[`~PreTrainedTokenizer.apply_chat_template`]测试,
+然后将更新后的`tokenizer`推送到 Hub。
+即使您不是模型所有者,如果您正在使用一个空的聊天模板或者仍在使用默认的聊天模板,
+请发起一个[pull request](https://huggingface.co/docs/hub/repositories-pull-requests-discussions),以便正确设置该属性!
+
+一旦属性设置完成,就完成了!`tokenizer.apply_chat_template`现在将在该模型中正常工作,
+这意味着它也会自动支持在诸如`TextGenerationPipeline`的地方!
+
+通过确保模型具有这一属性,我们可以确保整个社区都能充分利用开源模型的全部功能。
+格式不匹配已经困扰这个领域并悄悄地损害了性能太久了,是时候结束它们了!
+
+
+## 高级:模板写作技巧
+
+如果你对Jinja不熟悉,我们通常发现编写聊天模板的最简单方法是先编写一个简短的Python脚本,按照你想要的方式格式化消息,然后将该脚本转换为模板。
+
+请记住,模板处理程序将接收对话历史作为名为`messages`的变量。每条`message`都是一个带有两个键`role`和`content`的字典。
+您可以在模板中像在Python中一样访问`messages`,这意味着您可以使用`{% for message in messages %}`进行循环,
+或者例如使用`{{ messages[0] }}`访问单个消息。
+
+您也可以使用以下提示将您的代码转换为Jinja:
+### For循环
+
+在Jinja中,for循环看起来像这样:
+
+```
+{% for message in messages %}
+{{ message['content'] }}
+{% endfor %}
+```
+
+请注意,`{{ expression block }}`中的内容将被打印到输出。您可以在表达式块中使用像`+`这样的运算符来组合字符串。
+### If语句
+
+Jinja中的if语句如下所示:
+
+```
+{% if message['role'] == 'user' %}
+{{ message['content'] }}
+{% endif %}
+```
+注意Jinja使用`{% endfor %}`和`{% endif %}`来表示`for`和`if`的结束。
+
+### 特殊变量
+
+在您的模板中,您将可以访问`messages`列表,但您还可以访问其他几个特殊变量。
+这些包括特殊`token`,如`bos_token`和`eos_token`,以及我们上面讨论过的`add_generation_prompt`变量。
+您还可以使用`loop`变量来访问有关当前循环迭代的信息,例如使用`{% if loop.last %}`来检查当前消息是否是对话中的最后一条消息。
+
+以下是一个示例,如果`add_generation_prompt=True`需要在对话结束时添加`generate_prompt`:
+
+
+```
+{% if loop.last and add_generation_prompt %}
+{{ bos_token + 'Assistant:\n' }}
+{% endif %}
+```
+
+### 空格的注意事项
+
+我们已经尽可能尝试让Jinja忽略除`{{ expressions }}`之外的空格。
+然而,请注意Jinja是一个通用的模板引擎,它可能会将同一行文本块之间的空格视为重要,并将其打印到输出中。
+我们**强烈**建议在上传模板之前检查一下,确保模板没有在不应该的地方打印额外的空格!
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/community.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/community.md
new file mode 100644
index 0000000000000000000000000000000000000000..d9dd3938ed287717c020a147201faa733a745579
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/community.md
@@ -0,0 +1,69 @@
+
+
+# 社区
+
+这个页面汇集了社区开发的🤗Transformers相关的资源。
+
+## 社区资源
+
+| 资源 | 描述 | 作者 |
+|:----------|:-------------|------:|
+| [Hugging Face Transformers Glossary Flashcards](https://www.darigovresearch.com/huggingface-transformers-glossary-flashcards) | 这是一套基于 [Transformers文档术语表](glossary) 的抽认卡,它们已被整理成可以通过 [Anki](https://apps.ankiweb.net/) (一款专为长期知识保留而设计的开源、跨平台的应用)来进行学习和复习的形式。使用方法参见: [介绍如何使用抽认卡的视频](https://www.youtube.com/watch?v=Dji_h7PILrw)。 | [Darigov Research](https://www.darigovresearch.com/) |
+
+## 社区笔记本
+
+| 笔记本 | 描述 | 作者 | |
+|:----------|:-------------|:-------------|------:|
+| [Fine-tune a pre-trained Transformer to generate lyrics](https://github.com/AlekseyKorshuk/huggingartists) | 如何通过微调GPT-2模型来生成你最喜欢的艺术家风格的歌词 | [Aleksey Korshuk](https://github.com/AlekseyKorshuk) | [](https://colab.research.google.com/github/AlekseyKorshuk/huggingartists/blob/master/huggingartists-demo.ipynb) |
+| [Train T5 in Tensorflow 2](https://github.com/snapthat/TF-T5-text-to-text) | 如何使用 Tensorflow 2 训练 T5 可以完成任何任务。本笔记本演示了如何使用 SQUAD 在 Tensorflow 2 中实现问答任务 | [Muhammad Harris](https://github.com/HarrisDePerceptron) |[](https://colab.research.google.com/github/snapthat/TF-T5-text-to-text/blob/master/snapthatT5/notebooks/TF-T5-Datasets%20Training.ipynb) |
+| [Train T5 on TPU](https://github.com/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb) | 如何使用 Transformers 和 Nlp 在 SQUAD 上训练 T5 | [Suraj Patil](https://github.com/patil-suraj) |[](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb#scrollTo=QLGiFCDqvuil) |
+| [Fine-tune T5 for Classification and Multiple Choice](https://github.com/patil-suraj/exploring-T5/blob/master/t5_fine_tuning.ipynb) | 如何使用 PyTorch Lightning 的text-to-text格式对 T5 进行微调以完成分类和多项选择任务 | [Suraj Patil](https://github.com/patil-suraj) | [](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/t5_fine_tuning.ipynb) |
+| [Fine-tune DialoGPT on New Datasets and Languages](https://github.com/ncoop57/i-am-a-nerd/blob/master/_notebooks/2020-05-12-chatbot-part-1.ipynb) | 如何在新数据集上微调 DialoGPT 模型,以实现开放式对话聊天机器人 | [Nathan Cooper](https://github.com/ncoop57) | [](https://colab.research.google.com/github/ncoop57/i-am-a-nerd/blob/master/_notebooks/2020-05-12-chatbot-part-1.ipynb) |
+| [Long Sequence Modeling with Reformer](https://github.com/patrickvonplaten/notebooks/blob/master/PyTorch_Reformer.ipynb) | 如何使用 Reformer 对长达 500,000 个 token 的序列进行训练 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/PyTorch_Reformer.ipynb) |
+| [Fine-tune BART for Summarization](https://github.com/ohmeow/ohmeow_website/blob/master/posts/2021-05-25-mbart-sequence-classification-with-blurr.ipynb) | 如何使用 blurr 对 BART 进行微调,以便使用 fastai 进行汇总 | [Wayde Gilliam](https://ohmeow.com/) | [](https://colab.research.google.com/github/ohmeow/ohmeow_website/blob/master/posts/2021-05-25-mbart-sequence-classification-with-blurr.ipynb) |
+| [Fine-tune a pre-trained Transformer on anyone's tweets](https://colab.research.google.com/github/borisdayma/huggingtweets/blob/master/huggingtweets-demo.ipynb) | 如何通过微调 GPT-2 模型生成以你最喜欢的 Twitter 帐户风格发布的推文 | [Boris Dayma](https://github.com/borisdayma) | [](https://colab.research.google.com/github/borisdayma/huggingtweets/blob/master/huggingtweets-demo.ipynb) |
+| [Optimize 🤗 Hugging Face models with Weights & Biases](https://colab.research.google.com/github/wandb/examples/blob/master/colabs/huggingface/Optimize_Hugging_Face_models_with_Weights_%26_Biases.ipynb) | 展示 W&B 与 Hugging Face 集成的完整教程 | [Boris Dayma](https://github.com/borisdayma) | [](https://colab.research.google.com/github/wandb/examples/blob/master/colabs/huggingface/Optimize_Hugging_Face_models_with_Weights_%26_Biases.ipynb) |
+| [Pretrain Longformer](https://github.com/allenai/longformer/blob/master/scripts/convert_model_to_long.ipynb) | 如何构建现有预训练模型的“长”版本 | [Iz Beltagy](https://beltagy.net) | [](https://colab.research.google.com/github/allenai/longformer/blob/master/scripts/convert_model_to_long.ipynb) |
+| [Fine-tune Longformer for QA](https://github.com/patil-suraj/Notebooks/blob/master/longformer_qa_training.ipynb) | 如何针对问答任务微调长模型 | [Suraj Patil](https://github.com/patil-suraj) | [](https://colab.research.google.com/github/patil-suraj/Notebooks/blob/master/longformer_qa_training.ipynb) |
+| [Evaluate Model with 🤗nlp](https://github.com/patrickvonplaten/notebooks/blob/master/How_to_evaluate_Longformer_on_TriviaQA_using_NLP.ipynb) | 如何使用`nlp`库在TriviaQA数据集上评估Longformer模型| [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/drive/1m7eTGlPmLRgoPkkA7rkhQdZ9ydpmsdLE?usp=sharing) |
+| [Fine-tune T5 for Sentiment Span Extraction](https://github.com/enzoampil/t5-intro/blob/master/t5_qa_training_pytorch_span_extraction.ipynb) | 如何使用PyTorch Lightning以text-to-text的格式对T5进行微调,以进行情感跨度提取 | [Lorenzo Ampil](https://github.com/enzoampil) | [](https://colab.research.google.com/github/enzoampil/t5-intro/blob/master/t5_qa_training_pytorch_span_extraction.ipynb) |
+| [Fine-tune DistilBert for Multiclass Classification](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_multiclass_classification.ipynb) | 如何使用 PyTorch 微调 DistilBert 进行多类分类 | [Abhishek Kumar Mishra](https://github.com/abhimishra91) | [](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_multiclass_classification.ipynb)|
+|[Fine-tune BERT for Multi-label Classification](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_multi_label_classification.ipynb)|如何使用 PyTorch 对 BERT 进行微调以进行多标签分类|[Abhishek Kumar Mishra](https://github.com/abhimishra91) |[](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_multi_label_classification.ipynb)|
+|[Fine-tune T5 for Summarization](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_summarization_wandb.ipynb)|如何在 PyTorch 中微调 T5 进行总结并使用 WandB 跟踪实验|[Abhishek Kumar Mishra](https://github.com/abhimishra91) |[](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_summarization_wandb.ipynb)|
+|[Speed up Fine-Tuning in Transformers with Dynamic Padding / Bucketing](https://github.com/ELS-RD/transformers-notebook/blob/master/Divide_Hugging_Face_Transformers_training_time_by_2_or_more.ipynb)|如何通过使用动态填充/桶排序将微调速度提高两倍|[Michael Benesty](https://github.com/pommedeterresautee) |[](https://colab.research.google.com/drive/1CBfRU1zbfu7-ijiOqAAQUA-RJaxfcJoO?usp=sharing)|
+|[Pretrain Reformer for Masked Language Modeling](https://github.com/patrickvonplaten/notebooks/blob/master/Reformer_For_Masked_LM.ipynb)| 如何训练一个带有双向自注意力层的Reformer模型 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/drive/1tzzh0i8PgDQGV3SMFUGxM7_gGae3K-uW?usp=sharing)|
+|[Expand and Fine Tune Sci-BERT](https://github.com/lordtt13/word-embeddings/blob/master/COVID-19%20Research%20Data/COVID-SciBERT.ipynb)| 如何在 CORD 数据集上增加 AllenAI 预训练的 SciBERT 模型的词汇量,并对其进行流水线化 | [Tanmay Thakur](https://github.com/lordtt13) | [](https://colab.research.google.com/drive/1rqAR40goxbAfez1xvF3hBJphSCsvXmh8)|
+|[Fine Tune BlenderBotSmall for Summarization using the Trainer API](https://github.com/lordtt13/transformers-experiments/blob/master/Custom%20Tasks/fine-tune-blenderbot_small-for-summarization.ipynb)| 如何使用Trainer API在自定义数据集上对BlenderBotSmall进行微调以进行文本摘要 | [Tanmay Thakur](https://github.com/lordtt13) | [](https://colab.research.google.com/drive/19Wmupuls7mykSGyRN_Qo6lPQhgp56ymq?usp=sharing)|
+|[Fine-tune Electra and interpret with Integrated Gradients](https://github.com/elsanns/xai-nlp-notebooks/blob/master/electra_fine_tune_interpret_captum_ig.ipynb) | 如何对Electra模型进行微调以进行情感分析,并使用Captum集成梯度来解释预测结果 | [Eliza Szczechla](https://elsanns.github.io) | [](https://colab.research.google.com/github/elsanns/xai-nlp-notebooks/blob/master/electra_fine_tune_interpret_captum_ig.ipynb)|
+|[fine-tune a non-English GPT-2 Model with Trainer class](https://github.com/philschmid/fine-tune-GPT-2/blob/master/Fine_tune_a_non_English_GPT_2_Model_with_Huggingface.ipynb) | 如何使用 Trainer 类微调非英语 GPT-2 模型 | [Philipp Schmid](https://www.philschmid.de) | [](https://colab.research.google.com/github/philschmid/fine-tune-GPT-2/blob/master/Fine_tune_a_non_English_GPT_2_Model_with_Huggingface.ipynb)|
+|[Fine-tune a DistilBERT Model for Multi Label Classification task](https://github.com/DhavalTaunk08/Transformers_scripts/blob/master/Transformers_multilabel_distilbert.ipynb) | 如何针对多标签分类任务微调 DistilBERT 模型 | [Dhaval Taunk](https://github.com/DhavalTaunk08) | [](https://colab.research.google.com/github/DhavalTaunk08/Transformers_scripts/blob/master/Transformers_multilabel_distilbert.ipynb)|
+|[Fine-tune ALBERT for sentence-pair classification](https://github.com/NadirEM/nlp-notebooks/blob/master/Fine_tune_ALBERT_sentence_pair_classification.ipynb) | 如何针对句子对分类任务对 ALBERT 模型或其他基于 BERT 的模型进行微调 | [Nadir El Manouzi](https://github.com/NadirEM) | [](https://colab.research.google.com/github/NadirEM/nlp-notebooks/blob/master/Fine_tune_ALBERT_sentence_pair_classification.ipynb)|
+|[Fine-tune Roberta for sentiment analysis](https://github.com/DhavalTaunk08/NLP_scripts/blob/master/sentiment_analysis_using_roberta.ipynb) | 如何微调 Roberta 模型进行情绪分析 | [Dhaval Taunk](https://github.com/DhavalTaunk08) | [](https://colab.research.google.com/github/DhavalTaunk08/NLP_scripts/blob/master/sentiment_analysis_using_roberta.ipynb)|
+|[Evaluating Question Generation Models](https://github.com/flexudy-pipe/qugeev) | 你的 seq2seq 转换器模型生成的问题的答案有多准确? | [Pascal Zoleko](https://github.com/zolekode) | [](https://colab.research.google.com/drive/1bpsSqCQU-iw_5nNoRm_crPq6FRuJthq_?usp=sharing)|
+|[Classify text with DistilBERT and Tensorflow](https://github.com/peterbayerle/huggingface_notebook/blob/main/distilbert_tf.ipynb) | 如何在 TensorFlow 中微调 DistilBERT 以进行文本分类 | [Peter Bayerle](https://github.com/peterbayerle) | [](https://colab.research.google.com/github/peterbayerle/huggingface_notebook/blob/main/distilbert_tf.ipynb)|
+|[Leverage BERT for Encoder-Decoder Summarization on CNN/Dailymail](https://github.com/patrickvonplaten/notebooks/blob/master/BERT2BERT_for_CNN_Dailymail.ipynb) | 如何在CNN/Dailymail摘要任务上使用*google-bert/bert-base-uncased*检查点对*EncoderDecoderModel*进行热启动 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/BERT2BERT_for_CNN_Dailymail.ipynb)|
+|[Leverage RoBERTa for Encoder-Decoder Summarization on BBC XSum](https://github.com/patrickvonplaten/notebooks/blob/master/RoBERTaShared_for_BBC_XSum.ipynb) | 如何在BBC/XSum摘要任务上使用*FacebookAI/roberta-base*检查点对共享的*EncoderDecoderModel*进行热启动 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/RoBERTaShared_for_BBC_XSum.ipynb)|
+|[Fine-tune TAPAS on Sequential Question Answering (SQA)](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb) | 如何在Sequential Question Answering (SQA)数据集上使用*tapas-base*检查点对*TapasForQuestionAnswering*进行微调 | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb)|
+|[Evaluate TAPAS on Table Fact Checking (TabFact)](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Evaluating_TAPAS_on_the_Tabfact_test_set.ipynb) | 如何结合使用 🤗 数据集和 🤗 transformers 库,使用*tapas-base-finetuned-tabfact*检查点评估经过微调的*TapasForSequenceClassification* | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Evaluating_TAPAS_on_the_Tabfact_test_set.ipynb)|
+|[Fine-tuning mBART for translation](https://colab.research.google.com/github/vasudevgupta7/huggingface-tutorials/blob/main/translation_training.ipynb) | 如何使用 Seq2SeqTrainer 对 mBART 进行微调以实现印地语到英语的翻译 | [Vasudev Gupta](https://github.com/vasudevgupta7) | [](https://colab.research.google.com/github/vasudevgupta7/huggingface-tutorials/blob/main/translation_training.ipynb)|
+|[Fine-tune LayoutLM on FUNSD (a form understanding dataset)](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForTokenClassification_on_FUNSD.ipynb) | 如何在FUNSD数据集上对*LayoutLMForTokenClassification*进行微调以从扫描文档中提取信息 | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForTokenClassification_on_FUNSD.ipynb)|
+|[Fine-Tune DistilGPT2 and Generate Text](https://colab.research.google.com/github/tripathiaakash/DistilGPT2-Tutorial/blob/main/distilgpt2_fine_tuning.ipynb) | 如何微调 DistilGPT2 并生成文本 | [Aakash Tripathi](https://github.com/tripathiaakash) | [](https://colab.research.google.com/github/tripathiaakash/DistilGPT2-Tutorial/blob/main/distilgpt2_fine_tuning.ipynb)|
+|[Fine-Tune LED on up to 8K tokens](https://github.com/patrickvonplaten/notebooks/blob/master/Fine_tune_Longformer_Encoder_Decoder_(LED)_for_Summarization_on_pubmed.ipynb) | 如何对LED模型在PubMed数据集上进行微调以进行长文本摘要 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/Fine_tune_Longformer_Encoder_Decoder_(LED)_for_Summarization_on_pubmed.ipynb)|
+|[Evaluate LED on Arxiv](https://github.com/patrickvonplaten/notebooks/blob/master/LED_on_Arxiv.ipynb) | 如何有效评估LED模型的长远发展 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/LED_on_Arxiv.ipynb)|
+|[Fine-tune LayoutLM on RVL-CDIP (a document image classification dataset)](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForSequenceClassification_on_RVL_CDIP.ipynb) | 如何在 RVL-CDIP 数据集上微调*LayoutLMForSequenceClassification*以进行扫描文档分类 | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForSequenceClassification_on_RVL_CDIP.ipynb)|
+|[Wav2Vec2 CTC decoding with GPT2 adjustment](https://github.com/voidful/huggingface_notebook/blob/main/xlsr_gpt.ipynb) | 如何通过语言模型调整解码 CTC 序列 | [Eric Lam](https://github.com/voidful) | [](https://colab.research.google.com/drive/1e_z5jQHYbO2YKEaUgzb1ww1WwiAyydAj?usp=sharing)|
+|[Fine-tune BART for summarization in two languages with Trainer class](https://github.com/elsanns/xai-nlp-notebooks/blob/master/fine_tune_bart_summarization_two_langs.ipynb) | 如何使用Trainer类对BART模型进行多语言摘要任务的微调 | [Eliza Szczechla](https://github.com/elsanns) | [](https://colab.research.google.com/github/elsanns/xai-nlp-notebooks/blob/master/fine_tune_bart_summarization_two_langs.ipynb)|
+|[Evaluate Big Bird on Trivia QA](https://github.com/patrickvonplaten/notebooks/blob/master/Evaluating_Big_Bird_on_TriviaQA.ipynb) | 评估BigBird模型在长文档问答任务上的性能,特别是在Trivia QA数据集上| [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/Evaluating_Big_Bird_on_TriviaQA.ipynb)|
+| [Create video captions using Wav2Vec2](https://github.com/Muennighoff/ytclipcc/blob/main/wav2vec_youtube_captions.ipynb) | 如何使用Wav2Vec对任何视频的音频进行转录以创建YouTube字幕 | [Niklas Muennighoff](https://github.com/Muennighoff) |[](https://colab.research.google.com/github/Muennighoff/ytclipcc/blob/main/wav2vec_youtube_captions.ipynb) |
+| [Fine-tune the Vision Transformer on CIFAR-10 using PyTorch Lightning](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_PyTorch_Lightning.ipynb) | 如何使用HuggingFace的Transformers、Datasets和PyTorch Lightning在CIFAR-10数据集上对Vision Transformer(ViT)进行微调 | [Niels Rogge](https://github.com/nielsrogge) |[](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_PyTorch_Lightning.ipynb) |
+| [Fine-tune the Vision Transformer on CIFAR-10 using the 🤗 Trainer](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_the_%F0%9F%A4%97_Trainer.ipynb) | 如何使用HuggingFace的Transformers、Datasets和🤗 Trainer在CIFAR-10数据集上对Vision Transformer(ViT)进行微调| [Niels Rogge](https://github.com/nielsrogge) |[](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_the_%F0%9F%A4%97_Trainer.ipynb) |
+| [Evaluate LUKE on Open Entity, an entity typing dataset](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_open_entity.ipynb) | 如何在开放实体数据集上评估*LukeForEntityClassification*| [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_open_entity.ipynb) |
+| [Evaluate LUKE on TACRED, a relation extraction dataset](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_tacred.ipynb) | 如何在 TACRED 数据集上评估*LukeForEntityPairClassification* | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_tacred.ipynb) |
+| [Evaluate LUKE on CoNLL-2003, an important NER benchmark](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_conll_2003.ipynb) | 如何在 CoNLL-2003 数据集上评估*LukeForEntitySpanClassification* | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_conll_2003.ipynb) |
+| [Evaluate BigBird-Pegasus on PubMed dataset](https://github.com/vasudevgupta7/bigbird/blob/main/notebooks/bigbird_pegasus_evaluation.ipynb) | 如何在 PubMed 数据集上评估*BigBirdPegasusForConditionalGeneration*| [Vasudev Gupta](https://github.com/vasudevgupta7) | [](https://colab.research.google.com/github/vasudevgupta7/bigbird/blob/main/notebooks/bigbird_pegasus_evaluation.ipynb) |
+| [Speech Emotion Classification with Wav2Vec2](https://github.com/m3hrdadfi/soxan/blob/main/notebooks/Emotion_recognition_in_Greek_speech_using_Wav2Vec2.ipynb) |如何利用预训练的 Wav2Vec2 模型在 MEGA 数据集上进行情绪分类| [Mehrdad Farahani](https://github.com/m3hrdadfi) | [](https://colab.research.google.com/github/m3hrdadfi/soxan/blob/main/notebooks/Emotion_recognition_in_Greek_speech_using_Wav2Vec2.ipynb) |
+| [Detect objects in an image with DETR](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/DETR/DETR_minimal_example_(with_DetrFeatureExtractor).ipynb) | 如何使用经过训练的*DetrForObjectDetection*模型检测图像中的物体并可视化注意力 | [Niels Rogge](https://github.com/NielsRogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/DETR/DETR_minimal_example_(with_DetrFeatureExtractor).ipynb) |
+| [Fine-tune DETR on a custom object detection dataset](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/DETR/Fine_tuning_DetrForObjectDetection_on_custom_dataset_(balloon).ipynb) | 如何在自定义对象检测数据集上微调*DetrForObjectDetection* | [Niels Rogge](https://github.com/NielsRogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/DETR/Fine_tuning_DetrForObjectDetection_on_custom_dataset_(balloon).ipynb) |
+| [Finetune T5 for Named Entity Recognition](https://github.com/ToluClassics/Notebooks/blob/main/T5_Ner_Finetuning.ipynb) | 如何在命名实体识别任务中微调*T5*| [Ogundepo Odunayo](https://github.com/ToluClassics) | [](https://colab.research.google.com/drive/1obr78FY_cBmWY5ODViCmzdY6O1KB65Vc?usp=sharing) |
+| [Fine-Tuning Open-Source LLM using QLoRA with MLflow and PEFT](https://github.com/mlflow/mlflow/blob/master/docs/source/llms/transformers/tutorials/fine-tuning/transformers-peft.ipynb) | 如何使用[QLoRA](https://github.com/artidoro/qlora) 和[PEFT](https://huggingface.co/docs/peft/en/index)以内存高效的方式微调大型语言模型(LLM),同时使用 [MLflow](https://mlflow.org/docs/latest/llms/transformers/index.html)进行实验跟踪| [Yuki Watanabe](https://github.com/B-Step62) | [](https://colab.research.google.com/github/mlflow/mlflow/blob/master/docs/source/llms/transformers/tutorials/fine-tuning/transformers-peft.ipynb) |
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/contributing.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/contributing.md
new file mode 100644
index 0000000000000000000000000000000000000000..b525754359babc0976b8f151c513ff4bbd73d0cf
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/contributing.md
@@ -0,0 +1,331 @@
+
+
+# 为 🤗 Transformers 做贡献
+
+欢迎所有人为 🤗 Transformers 做出贡献,我们重视每个人的贡献。代码贡献并不是帮助社区的唯一途径。回答问题、帮助他人和改进文档也非常有价值。
+
+宣传 🤗 Transformers 也会帮助我们!比如在博客文章里介绍一下这个库是如何帮助你完成了很棒的项目,每次它帮助你时都在 Twitter 上大声宣传,或者给这个代码仓库点⭐️来表示感谢。
+
+无论你选择以哪种方式做出贡献,请注意并尊重我们的[行为准则](https://github.com/huggingface/transformers/blob/main/CODE_OF_CONDUCT.md)。
+
+**本指南的灵感来源于 [scikit-learn贡献指南](https://github.com/scikit-learn/scikit-learn/blob/main/CONTRIBUTING.md) ,它令人印象深刻.**
+
+## 做贡献的方法
+
+有多种方法可以为 🤗 Transformers 做贡献:
+
+* 修复现有代码中尚未解决的问题。
+* 提交与 bug 或所需新功能相关的 issue。
+* 实现新的模型。
+* 为示例或文档做贡献。
+
+如果你不知道从哪里开始,有一个特别的 [Good First Issue](https://github.com/huggingface/transformers/contribute) 列表。它会列出一些适合初学者的开放的 issues,并帮助你开始为开源项目做贡献。只需要在你想要处理的 issue 下发表评论就行。
+
+如果想要稍微更有挑战性的内容,你也可以查看 [Good Second Issue](https://github.com/huggingface/transformers/labels/Good%20Second%20Issue) 列表。总的来说,如果你觉得自己知道该怎么做,就去做吧,我们会帮助你达到目标的!🚀
+
+> 所有的贡献对社区来说都同样宝贵。🥰
+
+## 修复尚未解决的问题
+
+如果你发现现有代码中存在问题,并且已经想到了解决方法,请随时[开始贡献](https://github.com/huggingface/transformers/blob/main/CONTRIBUTING.md/#create-a-pull-request) 并创建一个 Pull Request!
+
+## 提交与 bug 相关的 issue 或功能请求
+
+在提交与错误相关的 issue 或功能请求时,请尽量遵循下面的指南。这能让我们更容易迅速回复你,并提供良好的反馈意见。
+
+### 你发现了 bug 吗?
+
+🤗 Transformers 之所以强大可靠,要感谢用户报告了他们遇到的问题。
+
+在提出issue之前,请你**确认该 bug 尚未被报告**(使用 GitHub 的 Issues 下面的搜索栏)。issue 也应该是与库本身的 bug 有关,而不是与你的代码有关。如果不确定 bug 是在你的代码中还是在库中,请先在[论坛](https://discuss.huggingface.co/)中询问。这有助于我们更快地解决与库相关的问题。
+
+一旦你确认该 bug 尚未被报告,请在你的 issue 中包含以下信息,以便我们快速解决:
+
+* 使用的**操作系统类型和版本**,以及 **Python**、**PyTorch** 和 **TensorFlow** 的版本。
+* 一个简短、独立的代码片段,可以让我们在不到30秒内重现这个问题。
+* 如果发生异常,请提供*完整的* traceback。
+* 附上你认为可能有帮助的任何其他附加信息,如屏幕截图。
+
+想要自动获取操作系统和软件版本,请运行以下命令:
+
+```bash
+transformers-cli env
+```
+
+你也可以从代码仓库的根目录下运行相同的命令:
+
+```bash
+python src/transformers/commands/transformers_cli.py env
+```
+
+### 你想要新功能吗?
+
+如果你希望在 🤗 Transformers 中看到新功能,请提出一个 issue 并包含以下内容:
+
+1. 这个新功能的*动机*是什么呢?是因为使用这个库时遇到了问题或者感到了某种不满吗?是因为你的项目需要这个功能吗?或者是你自己开发了某项内容,并且认为它可能会对社区有所帮助?
+
+ 不管是什么,我们都很想听!
+
+2. 请尽可能详细地描述你想要的功能。你告诉我们的越多,我们就能更好地帮助你。
+3. 请提供一个*代码片段*,演示该功能的使用方法。
+4. 如果这个功能与某篇论文相关,请包含链接。
+
+如果你描述得足够清晰,那么在你创建 issue 时,我们已经完成了80%的工作。
+
+我们已经添加了[模板](https://github.com/huggingface/transformers/tree/main/templates),可能有助于你提出 issue。
+
+## 你想要实现一个新模型吗?
+
+我们会持续发布新模型,如果你想要实现一个新模型,请提供以下信息:
+
+* 模型的简要描述和论文链接。
+* 如果实现是开源的,请提供实现的链接。
+* 如果模型权重可用,请提供模型权重的链接。
+
+如果你想亲自贡献模型,请告诉我们。让我们帮你把它添加到 🤗 Transformers!
+
+我们还有一个更技术性的指南,告诉你[如何将模型添加到 🤗 Transformers](https://huggingface.co/docs/transformers/add_new_model)。
+
+## 你想要添加文档吗?
+
+我们始终在寻求改进文档,使其更清晰准确。请告诉我们如何改进文档,比如拼写错误以及任何缺失、不清楚或不准确的内容。我们非常乐意进行修改,如果你有兴趣,我们也可以帮助你做出贡献!
+
+有关如何生成、构建和编写文档的更多详细信息,请查看文档 [README](https://github.com/huggingface/transformers/tree/main/docs)。
+
+## 创建 Pull Request
+
+在开始编写任何代码之前,我们强烈建议你先搜索现有的 PR(Pull Request) 或 issue,以确保没有其他人已经在做同样的事情。如果你不确定,提出 issue 来获取反馈意见是一个好办法。
+
+要为 🤗 Transformers 做贡献,你需要基本的 `git` 使用技能。虽然 `git` 不是一个很容易使用的工具,但它提供了非常全面的手册,在命令行中输入 `git --help` 并享受吧!如果你更喜欢书籍,[Pro Git](https://git-scm.com/book/en/v2)是一本很好的参考书。
+
+要为 🤗 Transformers 做贡献,你需要 **[Python 3.9](https://github.com/huggingface/transformers/blob/main/setup.py#L426)** 或更高版本。请按照以下步骤开始贡献:
+
+1. 点击[仓库](https://github.com/huggingface/transformers)页面上的 **[Fork](https://github.com/huggingface/transformers/fork)** 按钮,这会在你的 GitHub 账号下拷贝一份代码。
+
+2. 把派生仓库克隆到本地磁盘,并将基础仓库添加为远程仓库:
+
+ ```bash
+ git clone git@github.com:/transformers.git
+ cd transformers
+ git remote add upstream https://github.com/huggingface/transformers.git
+ ```
+
+3. 创建一个新的分支来保存你的更改:
+
+ ```bash
+ git checkout -b a-descriptive-name-for-my-changes
+ ```
+
+ 🚨 **不要**在 `main` 分支工作!
+
+4. 在虚拟环境中运行以下命令来设置开发环境:
+
+ ```bash
+ pip install -e ".[dev]"
+ ```
+
+ 如果在虚拟环境中已经安装了 🤗 Transformers,请先使用 `pip uninstall transformers` 卸载它,然后再用 `-e` 参数以可编辑模式重新安装。
+
+ 根据你的操作系统,以及 Transformers 的可选依赖项数量的增加,可能会在执行此命令时出现失败。如果出现这种情况,请确保已经安装了你想使用的深度学习框架(PyTorch, TensorFlow 和 Flax),然后执行以下操作:
+
+ ```bash
+ pip install -e ".[quality]"
+ ```
+
+ 大多数情况下,这些应该够用了。
+
+5. 在你的分支上开发相关功能。
+
+ 在编写代码时,请确保测试套件通过。用下面的方式运行受你的更改影响的测试:
+
+ ```bash
+ pytest tests/.py
+ ```
+
+ 想了解更多关于测试的信息,请阅读[测试](https://huggingface.co/docs/transformers/testing)指南。
+
+ 🤗 Transformers 使用 `black` 和 `ruff` 来保持代码风格的一致性。进行更改后,使用以下命令自动执行格式更正和代码验证:
+
+ ```bash
+ make fixup
+ ```
+
+ 它已经被优化为仅适用于你创建的 PR 所修改过的文件。
+
+ 如果想要逐个运行检查,可以使用以下命令:
+
+ ```bash
+ make style
+ ```
+
+ 🤗 Transformers 还使用了 `ruff` 和一些自定义脚本来检查编码错误。虽然质量管理是通过 CI 进行的,但你也可以使用以下命令来运行相同的检查:
+
+ ```bash
+ make quality
+ ```
+
+ 最后,我们有许多脚本来确保在添加新模型时不会忘记更新某些文件。你可以使用以下命令运行这些脚本:
+
+ ```bash
+ make repo-consistency
+ ```
+
+ 想要了解有关这些检查及如何解决相关问题的更多信息,请阅读 [检查 Pull Request](https://huggingface.co/docs/transformers/pr_checks) 指南。
+
+ 如果你修改了 `docs/source` 目录下的文档,请确保文档仍然能够被构建。这个检查也会在你创建 PR 时在 CI 中运行。如果要进行本地检查,请确保安装了文档构建工具:
+
+ ```bash
+ pip install ".[docs]"
+ ```
+
+ 在仓库的根目录下运行以下命令:
+
+ ```bash
+ doc-builder build transformers docs/source/en --build_dir ~/tmp/test-build
+ ```
+
+ 这将会在 `~/tmp/test-build` 文件夹中构建文档,你可以使用自己喜欢的编辑器查看生成的 Markdown 文件。当你创建 PR 时,也可以在GitHub上预览文档。
+
+ 当你对修改满意后,使用 `git add` 把修改的文件添加到暂存区,然后使用 `git commit` 在本地记录你的更改:
+
+ ```bash
+ git add modified_file.py
+ git commit
+ ```
+
+ 请记得写一个[好的提交信息](https://chris.beams.io/posts/git-commit/)来清晰地传达你所做的更改!
+
+ 为了保持你的代码副本与原始仓库的最新状态一致,在你创建 PR *之前*或者在管理员要求的情况下,把你的分支在 `upstream/branch` 上进行 rebase:
+
+ ```bash
+ git fetch upstream
+ git rebase upstream/main
+ ```
+
+ 把你的更改推送到你的分支:
+
+ ```bash
+ git push -u origin a-descriptive-name-for-my-changes
+ ```
+
+ 如果你已经创建了一个 PR,你需要使用 `--force` 参数进行强制推送。如果 PR 还没有被创建,你可以正常推送你的更改。
+
+6. 现在你可以转到 GitHub 上你的账号下的派生仓库,点击 **Pull Request** 来创建一个 PR。 请确保勾选我们 [checklist](https://github.com/huggingface/transformers/blob/main/CONTRIBUTING.md/#pull-request-checklist) 下的所有项目。准备好这些后,可以将你的更改发送给项目管理员进行审查。
+
+7. 如果管理员要求你进行更改,别气馁,我们的核心贡献者也会经历相同的事情!请在你的本地分支上进行工作,并将更改推送到派生仓库,以便于每个人都可以在 PR 中看到你的更改。这样它们会自动出现在 PR 中。
+
+### Pull request 的检查清单
+
+☐ Pull request 的标题应该总结你的贡献内容。
+
+记得指定一个*子文件夹的路径或测试文件*来运行测试。否则你将会运行 `tests` 或 `examples` 文件夹中的所有测试,它会花费很长时间!
+
+
+
+```bash
+RUN_SLOW=yes python -m pytest -n auto --dist=loadfile -s -v ./tests/models/my_new_model
+RUN_SLOW=yes python -m pytest -n auto --dist=loadfile -s -v ./examples/pytorch/text-classification
+```
+
+和时间较长的测试一样,还有其他环境变量在测试过程中,在默认情况下是未启用的:
+- `RUN_CUSTOM_TOKENIZERS`: 启用自定义分词器的测试。
+- `RUN_PT_FLAX_CROSS_TESTS`: 启用 PyTorch + Flax 整合的测试。
+- `RUN_PT_TF_CROSS_TESTS`: 启用 TensorFlow + PyTorch 整合的测试。
+
+更多环境变量和额外信息可以在 [testing_utils.py](src/transformers/testing_utils.py) 中找到。
+
+🤗 Transformers 只是使用 `pytest` 作为测试运行程序,但测试套件本身没用任何与 `pytest` 相关的功能。
+
+这意味着完全支持 `unittest` 。以下是如何使用 `unittest` 运行测试的方法:
+
+```bash
+python -m unittest discover -s tests -t . -v
+python -m unittest discover -s examples -t examples -v
+```
+
+### 风格指南
+
+🤗 Transformers 的文档遵循 [Google Python Style Guide](https://google.github.io/styleguide/pyguide.html)。请查看我们的 [文档编写指南](https://github.com/huggingface/transformers/tree/main/docs#writing-documentation---specification) 来获取更多信息。
+
+### 在 Windows 上开发
+
+在 Windows 上(除非你正在使用 [Windows Subsystem for Linux](https://learn.microsoft.com/en-us/windows/wsl/) 或 WSL),你需要配置 git 将 Windows 的 `CRLF` 行结束符转换为 Linux 的 `LF` 行结束符:
+
+```bash
+git config core.autocrlf input
+```
+
+在 Windows 上有一种方法可以运行 `make` 命令,那就是使用 MSYS2:
+
+1. [下载 MSYS2](https://www.msys2.org/),假设已经安装在 `C:\msys64`。
+2. 从命令行打开 `C:\msys64\msys2.exe` (可以在 **开始** 菜单中找到)。
+3. 在 shell 中运行: `pacman -Syu` ,并使用 `pacman -S make` 安装 `make`。
+4. 把 `C:\msys64\usr\bin` 添加到你的 PATH 环境变量中。
+
+现在你可以在任何终端(PowerShell、cmd.exe 等)中使用 `make` 命令了! 🎉
+
+### 将派生仓库与上游主仓库(Hugging Face 仓库)同步
+
+更新派生仓库的主分支时,请按照以下步骤操作。这是为了避免向每个上游 PR 添加参考注释,同时避免向参与这些 PR 的开发人员发送不必要的通知。
+
+1. 可以的话,请避免使用派生仓库上的分支和 PR 来与上游进行同步,而是直接合并到派生仓库的主分支。
+2. 如果确实需要一个 PR,在检查你的分支后,请按照以下步骤操作:
+
+ ```bash
+ git checkout -b your-branch-for-syncing
+ git pull --squash --no-commit upstream main
+ git commit -m ''
+ git push --set-upstream origin your-branch-for-syncing
+ ```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/create_a_model.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/create_a_model.md
new file mode 100644
index 0000000000000000000000000000000000000000..fd07497e7abf3a1740083917a0a9c3b7a5fa86ba
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/create_a_model.md
@@ -0,0 +1,389 @@
+
+
+# 创建自定义架构
+
+[`AutoClass`](model_doc/auto) 自动推断模型架构并下载预训练的配置和权重。一般来说,我们建议使用 `AutoClass` 生成与检查点(checkpoint)无关的代码。希望对特定模型参数有更多控制的用户,可以仅从几个基类创建自定义的 🤗 Transformers 模型。这对于任何有兴趣学习、训练或试验 🤗 Transformers 模型的人可能特别有用。通过本指南,深入了解如何不通过 `AutoClass` 创建自定义模型。了解如何:
+
+- 加载并自定义模型配置。
+- 创建模型架构。
+- 为文本创建慢速和快速分词器。
+- 为视觉任务创建图像处理器。
+- 为音频任务创建特征提取器。
+- 为多模态任务创建处理器。
+
+## 配置
+
+[配置](main_classes/configuration) 涉及到模型的具体属性。每个模型配置都有不同的属性;例如,所有 NLP 模型都共享 `hidden_size`、`num_attention_heads`、 `num_hidden_layers` 和 `vocab_size` 属性。这些属性用于指定构建模型时的注意力头数量或隐藏层层数。
+
+访问 [`DistilBertConfig`] 以更近一步了解 [DistilBERT](model_doc/distilbert),检查它的属性:
+
+```py
+>>> from transformers import DistilBertConfig
+
+>>> config = DistilBertConfig()
+>>> print(config)
+DistilBertConfig {
+ "activation": "gelu",
+ "attention_dropout": 0.1,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+[`DistilBertConfig`] 显示了构建基础 [`DistilBertModel`] 所使用的所有默认属性。所有属性都可以进行自定义,为实验创造了空间。例如,您可以将默认模型自定义为:
+
+- 使用 `activation` 参数尝试不同的激活函数。
+- 使用 `attention_dropout` 参数为 attention probabilities 使用更高的 dropout ratio。
+
+```py
+>>> my_config = DistilBertConfig(activation="relu", attention_dropout=0.4)
+>>> print(my_config)
+DistilBertConfig {
+ "activation": "relu",
+ "attention_dropout": 0.4,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+预训练模型的属性可以在 [`~PretrainedConfig.from_pretrained`] 函数中进行修改:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("distilbert/distilbert-base-uncased", activation="relu", attention_dropout=0.4)
+```
+
+当你对模型配置满意时,可以使用 [`~PretrainedConfig.save_pretrained`] 来保存配置。你的配置文件将以 JSON 文件的形式存储在指定的保存目录中:
+
+```py
+>>> my_config.save_pretrained(save_directory="./your_model_save_path")
+```
+
+要重用配置文件,请使用 [`~PretrainedConfig.from_pretrained`] 进行加载:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/config.json")
+```
+
+
+
+你还可以将配置文件保存为字典,甚至只保存自定义配置属性与默认配置属性之间的差异!有关更多详细信息,请参阅 [配置](main_classes/configuration) 文档。
+
+
+
+## 模型
+
+接下来,创建一个[模型](main_classes/models)。模型,也可泛指架构,定义了每一层网络的行为以及进行的操作。配置中的 `num_hidden_layers` 等属性用于定义架构。每个模型都共享基类 [`PreTrainedModel`] 和一些常用方法,例如调整输入嵌入的大小和修剪自注意力头。此外,所有模型都是 [`torch.nn.Module`](https://pytorch.org/docs/stable/generated/torch.nn.Module.html)、[`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) 或 [`flax.linen.Module`](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html) 的子类。这意味着模型与各自框架的用法兼容。
+
+
+
+将自定义配置属性加载到模型中:
+
+```py
+>>> from transformers import DistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/config.json")
+>>> model = DistilBertModel(my_config)
+```
+
+这段代码创建了一个具有随机参数而不是预训练权重的模型。在训练该模型之前,您还无法将该模型用于任何用途。训练是一项昂贵且耗时的过程。通常来说,最好使用预训练模型来更快地获得更好的结果,同时仅使用训练所需资源的一小部分。
+
+使用 [`~PreTrainedModel.from_pretrained`] 创建预训练模型:
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+当加载预训练权重时,如果模型是由 🤗 Transformers 提供的,将自动加载默认模型配置。然而,如果你愿意,仍然可以将默认模型配置的某些或者所有属性替换成你自己的配置:
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+将自定义配置属性加载到模型中:
+
+```py
+>>> from transformers import TFDistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+>>> tf_model = TFDistilBertModel(my_config)
+```
+
+这段代码创建了一个具有随机参数而不是预训练权重的模型。在训练该模型之前,您还无法将该模型用于任何用途。训练是一项昂贵且耗时的过程。通常来说,最好使用预训练模型来更快地获得更好的结果,同时仅使用训练所需资源的一小部分。
+
+使用 [`~TFPreTrainedModel.from_pretrained`] 创建预训练模型:
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+当加载预训练权重时,如果模型是由 🤗 Transformers 提供的,将自动加载默认模型配置。然而,如果你愿意,仍然可以将默认模型配置的某些或者所有属性替换成自己的配置:
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+
+### 模型头(Model heads)
+
+此时,你已经有了一个输出*隐藏状态*的基础 DistilBERT 模型。隐藏状态作为输入传递到模型头以生成最终输出。🤗 Transformers 为每个任务提供不同的模型头,只要模型支持该任务(即,您不能使用 DistilBERT 来执行像翻译这样的序列到序列任务)。
+
+
+
+例如,[`DistilBertForSequenceClassification`] 是一个带有序列分类头(sequence classification head)的基础 DistilBERT 模型。序列分类头是池化输出之上的线性层。
+
+```py
+>>> from transformers import DistilBertForSequenceClassification
+
+>>> model = DistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+通过切换到不同的模型头,可以轻松地将此检查点重复用于其他任务。对于问答任务,你可以使用 [`DistilBertForQuestionAnswering`] 模型头。问答头(question answering head)与序列分类头类似,不同点在于它是隐藏状态输出之上的线性层。
+
+```py
+>>> from transformers import DistilBertForQuestionAnswering
+
+>>> model = DistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+例如,[`TFDistilBertForSequenceClassification`] 是一个带有序列分类头(sequence classification head)的基础 DistilBERT 模型。序列分类头是池化输出之上的线性层。
+
+```py
+>>> from transformers import TFDistilBertForSequenceClassification
+
+>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+通过切换到不同的模型头,可以轻松地将此检查点重复用于其他任务。对于问答任务,你可以使用 [`TFDistilBertForQuestionAnswering`] 模型头。问答头(question answering head)与序列分类头类似,不同点在于它是隐藏状态输出之上的线性层。
+
+```py
+>>> from transformers import TFDistilBertForQuestionAnswering
+
+>>> tf_model = TFDistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+## 分词器
+
+在将模型用于文本数据之前,你需要的最后一个基类是 [tokenizer](main_classes/tokenizer),它用于将原始文本转换为张量。🤗 Transformers 支持两种类型的分词器:
+
+- [`PreTrainedTokenizer`]:分词器的Python实现
+- [`PreTrainedTokenizerFast`]:来自我们基于 Rust 的 [🤗 Tokenizer](https://huggingface.co/docs/tokenizers/python/latest/) 库的分词器。因为其使用了 Rust 实现,这种分词器类型的速度要快得多,尤其是在批量分词(batch tokenization)的时候。快速分词器还提供其他的方法,例如*偏移映射(offset mapping)*,它将标记(token)映射到其原始单词或字符。
+
+这两种分词器都支持常用的方法,如编码和解码、添加新标记以及管理特殊标记。
+
+
+
+并非每个模型都支持快速分词器。参照这张 [表格](index#supported-frameworks) 查看模型是否支持快速分词器。
+
+
+
+如果您训练了自己的分词器,则可以从*词表*文件创建一个分词器:
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> my_tokenizer = DistilBertTokenizer(vocab_file="my_vocab_file.txt", do_lower_case=False, padding_side="left")
+```
+
+请务必记住,自定义分词器生成的词表与预训练模型分词器生成的词表是不同的。如果使用预训练模型,则需要使用预训练模型的词表,否则输入将没有意义。 使用 [`DistilBertTokenizer`] 类创建具有预训练模型词表的分词器:
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> slow_tokenizer = DistilBertTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+使用 [`DistilBertTokenizerFast`] 类创建快速分词器:
+
+```py
+>>> from transformers import DistilBertTokenizerFast
+
+>>> fast_tokenizer = DistilBertTokenizerFast.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+默认情况下,[`AutoTokenizer`] 将尝试加载快速标记生成器。你可以通过在 `from_pretrained` 中设置 `use_fast=False` 以禁用此行为。
+
+
+
+## 图像处理器
+
+图像处理器用于处理视觉输入。它继承自 [`~image_processing_utils.ImageProcessingMixin`] 基类。
+
+要使用它,需要创建一个与你使用的模型关联的图像处理器。例如,如果你使用 [ViT](model_doc/vit) 进行图像分类,可以创建一个默认的 [`ViTImageProcessor`]:
+
+```py
+>>> from transformers import ViTImageProcessor
+
+>>> vit_extractor = ViTImageProcessor()
+>>> print(vit_extractor)
+ViTImageProcessor {
+ "do_normalize": true,
+ "do_resize": true,
+ "image_processor_type": "ViTImageProcessor",
+ "image_mean": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": 2,
+ "size": 224
+}
+```
+
+
+
+如果您不需要进行任何自定义,只需使用 `from_pretrained` 方法加载模型的默认图像处理器参数。
+
+
+
+修改任何 [`ViTImageProcessor`] 参数以创建自定义图像处理器:
+
+```py
+>>> from transformers import ViTImageProcessor
+
+>>> my_vit_extractor = ViTImageProcessor(resample="PIL.Image.BOX", do_normalize=False, image_mean=[0.3, 0.3, 0.3])
+>>> print(my_vit_extractor)
+ViTImageProcessor {
+ "do_normalize": false,
+ "do_resize": true,
+ "image_processor_type": "ViTImageProcessor",
+ "image_mean": [
+ 0.3,
+ 0.3,
+ 0.3
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": "PIL.Image.BOX",
+ "size": 224
+}
+```
+
+## 特征提取器
+
+特征提取器用于处理音频输入。它继承自 [`~feature_extraction_utils.FeatureExtractionMixin`] 基类,亦可继承 [`SequenceFeatureExtractor`] 类来处理音频输入。
+
+要使用它,创建一个与你使用的模型关联的特征提取器。例如,如果你使用 [Wav2Vec2](model_doc/wav2vec2) 进行音频分类,可以创建一个默认的 [`Wav2Vec2FeatureExtractor`]:
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> w2v2_extractor = Wav2Vec2FeatureExtractor()
+>>> print(w2v2_extractor)
+Wav2Vec2FeatureExtractor {
+ "do_normalize": true,
+ "feature_extractor_type": "Wav2Vec2FeatureExtractor",
+ "feature_size": 1,
+ "padding_side": "right",
+ "padding_value": 0.0,
+ "return_attention_mask": false,
+ "sampling_rate": 16000
+}
+```
+
+
+
+如果您不需要进行任何自定义,只需使用 `from_pretrained` 方法加载模型的默认特征提取器参数。
+
+
+
+修改任何 [`Wav2Vec2FeatureExtractor`] 参数以创建自定义特征提取器:
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> w2v2_extractor = Wav2Vec2FeatureExtractor(sampling_rate=8000, do_normalize=False)
+>>> print(w2v2_extractor)
+Wav2Vec2FeatureExtractor {
+ "do_normalize": false,
+ "feature_extractor_type": "Wav2Vec2FeatureExtractor",
+ "feature_size": 1,
+ "padding_side": "right",
+ "padding_value": 0.0,
+ "return_attention_mask": false,
+ "sampling_rate": 8000
+}
+```
+
+
+## 处理器
+
+对于支持多模式任务的模型,🤗 Transformers 提供了一个处理器类,可以方便地将特征提取器和分词器等处理类包装到单个对象中。例如,让我们使用 [`Wav2Vec2Processor`] 来执行自动语音识别任务 (ASR)。 ASR 将音频转录为文本,因此您将需要一个特征提取器和一个分词器。
+
+创建一个特征提取器来处理音频输入:
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> feature_extractor = Wav2Vec2FeatureExtractor(padding_value=1.0, do_normalize=True)
+```
+
+创建一个分词器来处理文本输入:
+
+```py
+>>> from transformers import Wav2Vec2CTCTokenizer
+
+>>> tokenizer = Wav2Vec2CTCTokenizer(vocab_file="my_vocab_file.txt")
+```
+
+将特征提取器和分词器合并到 [`Wav2Vec2Processor`] 中:
+
+```py
+>>> from transformers import Wav2Vec2Processor
+
+>>> processor = Wav2Vec2Processor(feature_extractor=feature_extractor, tokenizer=tokenizer)
+```
+
+通过两个基类 - 配置类和模型类 - 以及一个附加的预处理类(分词器、图像处理器、特征提取器或处理器),你可以创建 🤗 Transformers 支持的任何模型。 每个基类都是可配置的,允许你使用所需的特定属性。 你可以轻松设置模型进行训练或修改现有的预训练模型进行微调。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/custom_models.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/custom_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..209e593506e8fb152f247b9e11e021b1ee45a72f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/custom_models.md
@@ -0,0 +1,305 @@
+
+
+# 共享自定义模型
+
+🤗 Transformers 库设计得易于扩展。每个模型的代码都在仓库给定的子文件夹中,没有进行抽象,因此你可以轻松复制模型代码文件并根据需要进行调整。
+
+如果你要编写全新的模型,从头开始可能更容易。在本教程中,我们将向你展示如何编写自定义模型及其配置,以便可以在 Transformers 中使用它;以及如何与社区共享它(及其依赖的代码),以便任何人都可以使用,即使它不在 🤗 Transformers 库中。
+
+我们将以 ResNet 模型为例,通过将 [timm 库](https://github.com/rwightman/pytorch-image-models) 的 ResNet 类封装到 [`PreTrainedModel`] 中来进行说明。
+
+## 编写自定义配置
+
+在深入研究模型之前,让我们首先编写其配置。模型的配置是一个对象,其中包含构建模型所需的所有信息。我们将在下一节中看到,模型只能接受一个 `config` 来进行初始化,因此我们很需要使该对象尽可能完整。
+
+我们将采用一些我们可能想要调整的 ResNet 类的参数举例。不同的配置将为我们提供不同类型可能的 ResNet 模型。在确认其中一些参数的有效性后,我们只需存储这些参数。
+
+```python
+from transformers import PretrainedConfig
+from typing import List
+
+
+class ResnetConfig(PretrainedConfig):
+ model_type = "resnet"
+
+ def __init__(
+ self,
+ block_type="bottleneck",
+ layers: List[int] = [3, 4, 6, 3],
+ num_classes: int = 1000,
+ input_channels: int = 3,
+ cardinality: int = 1,
+ base_width: int = 64,
+ stem_width: int = 64,
+ stem_type: str = "",
+ avg_down: bool = False,
+ **kwargs,
+ ):
+ if block_type not in ["basic", "bottleneck"]:
+ raise ValueError(f"`block_type` must be 'basic' or bottleneck', got {block_type}.")
+ if stem_type not in ["", "deep", "deep-tiered"]:
+ raise ValueError(f"`stem_type` must be '', 'deep' or 'deep-tiered', got {stem_type}.")
+
+ self.block_type = block_type
+ self.layers = layers
+ self.num_classes = num_classes
+ self.input_channels = input_channels
+ self.cardinality = cardinality
+ self.base_width = base_width
+ self.stem_width = stem_width
+ self.stem_type = stem_type
+ self.avg_down = avg_down
+ super().__init__(**kwargs)
+```
+
+编写自定义配置时需要记住的三个重要事项如下:
+- 必须继承自 `PretrainedConfig`,
+- `PretrainedConfig` 的 `__init__` 方法必须接受任何 kwargs,
+- 这些 `kwargs` 需要传递给超类的 `__init__` 方法。
+
+继承是为了确保你获得来自 🤗 Transformers 库的所有功能,而另外两个约束源于 `PretrainedConfig` 的字段比你设置的字段多。在使用 `from_pretrained` 方法重新加载配置时,这些字段需要被你的配置接受,然后传递给超类。
+
+为你的配置定义 `model_type`(此处为 `model_type="resnet"`)不是必须的,除非你想使用自动类注册你的模型(请参阅最后一节)。
+
+做完这些以后,就可以像使用库里任何其他模型配置一样,轻松地创建和保存配置。以下代码展示了如何创建并保存 resnet50d 配置:
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d_config.save_pretrained("custom-resnet")
+```
+
+这行代码将在 `custom-resnet` 文件夹内保存一个名为 `config.json` 的文件。然后,你可以使用 `from_pretrained` 方法重新加载配置:
+
+```py
+resnet50d_config = ResnetConfig.from_pretrained("custom-resnet")
+```
+
+你还可以使用 [`PretrainedConfig`] 类的任何其他方法,例如 [`~PretrainedConfig.push_to_hub`],直接将配置上传到 Hub。
+
+## 编写自定义模型
+
+有了 ResNet 配置后,就可以继续编写模型了。实际上,我们将编写两个模型:一个模型用于从一批图像中提取隐藏特征(类似于 [`BertModel`]),另一个模型适用于图像分类(类似于 [`BertForSequenceClassification`])。
+
+正如之前提到的,我们只会编写一个松散的模型包装,以使示例保持简洁。在编写此类之前,只需要建立起块类型(block types)与实际块类(block classes)之间的映射。然后,通过将所有内容传递给ResNet类,从配置中定义模型:
+
+```py
+from transformers import PreTrainedModel
+from timm.models.resnet import BasicBlock, Bottleneck, ResNet
+from .configuration_resnet import ResnetConfig
+
+
+BLOCK_MAPPING = {"basic": BasicBlock, "bottleneck": Bottleneck}
+
+
+class ResnetModel(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor):
+ return self.model.forward_features(tensor)
+```
+
+对用于进行图像分类的模型,我们只需更改前向方法:
+
+```py
+import torch
+
+
+class ResnetModelForImageClassification(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor, labels=None):
+ logits = self.model(tensor)
+ if labels is not None:
+ loss = torch.nn.functional.cross_entropy(logits, labels)
+ return {"loss": loss, "logits": logits}
+ return {"logits": logits}
+```
+
+在这两种情况下,请注意我们如何继承 `PreTrainedModel` 并使用 `config` 调用了超类的初始化(有点像编写常规的torch.nn.Module)。设置 `config_class` 的那行代码不是必须的,除非你想使用自动类注册你的模型(请参阅最后一节)。
+
+
+
+如果你的模型与库中的某个模型非常相似,你可以重用与该模型相同的配置。
+
+
+
+你可以让模型返回任何你想要的内容,但是像我们为 `ResnetModelForImageClassification` 做的那样返回一个字典,并在传递标签时包含loss,可以使你的模型能够在 [`Trainer`] 类中直接使用。只要你计划使用自己的训练循环或其他库进行训练,也可以使用其他输出格式。
+
+现在我们已经有了模型类,让我们创建一个:
+
+```py
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+```
+
+同样的,你可以使用 [`PreTrainedModel`] 的任何方法,比如 [`~PreTrainedModel.save_pretrained`] 或者 [`~PreTrainedModel.push_to_hub`]。我们将在下一节中使用第二种方法,并了解如何如何使用我们的模型的代码推送模型权重。但首先,让我们在模型内加载一些预训练权重。
+
+在你自己的用例中,你可能会在自己的数据上训练自定义模型。为了快速完成本教程,我们将使用 resnet50d 的预训练版本。由于我们的模型只是它的包装,转移这些权重将会很容易:
+
+```py
+import timm
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+现在让我们看看,如何确保在执行 [`~PreTrainedModel.save_pretrained`] 或 [`~PreTrainedModel.push_to_hub`] 时,模型的代码被保存。
+
+## 将代码发送到 Hub
+
+
+
+此 API 是实验性的,未来的发布中可能会有一些轻微的不兼容更改。
+
+
+
+首先,确保你的模型在一个 `.py` 文件中完全定义。只要所有文件都位于同一目录中,它就可以依赖于某些其他文件的相对导入(目前我们还不为子模块支持此功能)。对于我们的示例,我们将在当前工作目录中名为 `resnet_model` 的文件夹中定义一个 `modeling_resnet.py` 文件和一个 `configuration_resnet.py` 文件。 配置文件包含 `ResnetConfig` 的代码,模型文件包含 `ResnetModel` 和 `ResnetModelForImageClassification` 的代码。
+
+```
+.
+└── resnet_model
+ ├── __init__.py
+ ├── configuration_resnet.py
+ └── modeling_resnet.py
+```
+
+`__init__.py` 可以为空,它的存在只是为了让 Python 检测到 `resnet_model` 可以用作模块。
+
+
+
+如果从库中复制模型文件,你需要将文件顶部的所有相对导入替换为从 `transformers` 包中的导入。
+
+
+
+请注意,你可以重用(或子类化)现有的配置/模型。
+
+要与社区共享您的模型,请参照以下步骤:首先从新创建的文件中导入ResNet模型和配置:
+
+```py
+from resnet_model.configuration_resnet import ResnetConfig
+from resnet_model.modeling_resnet import ResnetModel, ResnetModelForImageClassification
+```
+
+接下来,你需要告诉库,当使用 `save_pretrained` 方法时,你希望复制这些对象的代码文件,并将它们正确注册到给定的 Auto 类(特别是对于模型),只需要运行以下代码:
+
+```py
+ResnetConfig.register_for_auto_class()
+ResnetModel.register_for_auto_class("AutoModel")
+ResnetModelForImageClassification.register_for_auto_class("AutoModelForImageClassification")
+```
+
+请注意,对于配置(只有一个自动类 [`AutoConfig`]),不需要指定自动类,但对于模型来说情况不同。 你的自定义模型可能适用于许多不同的任务,因此你必须指定哪一个自动类适合你的模型。
+
+接下来,让我们像之前一样创建配置和模型:
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+现在要将模型推送到集线器,请确保你已登录。你看可以在终端中运行以下命令:
+
+```bash
+huggingface-cli login
+```
+
+或者在笔记本中运行以下代码:
+
+```py
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+然后,可以这样将模型推送到自己的命名空间(或你所属的组织):
+
+```py
+resnet50d.push_to_hub("custom-resnet50d")
+```
+
+除了模型权重和 JSON 格式的配置外,这行代码也会复制 `custom-resnet50d` 文件夹内的模型以及配置的 `.py` 文件并将结果上传至 Hub。你可以在此[模型仓库](https://huggingface.co/sgugger/custom-resnet50d)中查看结果。
+
+有关推推送至 Hub 方法的更多信息,请参阅[共享教程](model_sharing)。
+
+## 使用带有自定义代码的模型
+
+可以使用自动类(auto-classes)和 `from_pretrained` 方法,使用模型仓库里带有自定义代码的配置、模型或分词器文件。所有上传到 Hub 的文件和代码都会进行恶意软件扫描(有关更多信息,请参阅 [Hub 安全](https://huggingface.co/docs/hub/security#malware-scanning) 文档), 但你仍应查看模型代码和作者,以避免在你的计算机上执行恶意代码。 设置 `trust_remote_code=True` 以使用带有自定义代码的模型:
+
+```py
+from transformers import AutoModelForImageClassification
+
+model = AutoModelForImageClassification.from_pretrained("sgugger/custom-resnet50d", trust_remote_code=True)
+```
+
+我们强烈建议为 `revision` 参数传递提交哈希(commit hash),以确保模型的作者没有使用一些恶意的代码行更新了代码(除非您完全信任模型的作者)。
+
+```py
+commit_hash = "ed94a7c6247d8aedce4647f00f20de6875b5b292"
+model = AutoModelForImageClassification.from_pretrained(
+ "sgugger/custom-resnet50d", trust_remote_code=True, revision=commit_hash
+)
+```
+
+在 Hub 上浏览模型仓库的提交历史时,有一个按钮可以轻松复制任何提交的提交哈希。
+
+## 将自定义代码的模型注册到自动类
+
+如果你在编写一个扩展 🤗 Transformers 的库,你可能想要扩展自动类以包含您自己的模型。这与将代码推送到 Hub 不同,因为用户需要导入你的库才能获取自定义模型(与从 Hub 自动下载模型代码相反)。
+
+只要你的配置 `model_type` 属性与现有模型类型不同,并且你的模型类有正确的 `config_class` 属性,你可以像这样将它们添加到自动类中:
+
+```py
+from transformers import AutoConfig, AutoModel, AutoModelForImageClassification
+
+AutoConfig.register("resnet", ResnetConfig)
+AutoModel.register(ResnetConfig, ResnetModel)
+AutoModelForImageClassification.register(ResnetConfig, ResnetModelForImageClassification)
+```
+
+请注意,将自定义配置注册到 [`AutoConfig`] 时,使用的第一个参数需要与自定义配置的 `model_type` 匹配;而将自定义模型注册到任何自动模型类时,使用的第一个参数需要与 `config_class` 匹配。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/debugging.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/debugging.md
new file mode 100644
index 0000000000000000000000000000000000000000..77746a694fce36a3b05aef6d45922f6a8afd89a6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/debugging.md
@@ -0,0 +1,308 @@
+
+
+# 调试
+
+## 多GPU网络问题调试
+
+当使用`DistributedDataParallel`和多个GPU进行训练或推理时,如果遇到进程和(或)节点之间的互联问题,您可以使用以下脚本来诊断网络问题。
+
+```bash
+wget https://raw.githubusercontent.com/huggingface/transformers/main/scripts/distributed/torch-distributed-gpu-test.py
+```
+
+例如,要测试两个GPU之间的互联,请执行以下操作:
+
+```bash
+python -m torch.distributed.run --nproc_per_node 2 --nnodes 1 torch-distributed-gpu-test.py
+```
+
+如果两个进程能够相互通信并分配GPU内存,它们各自将打印出 "OK" 状态。
+
+对于更多的GPU或节点,可以根据脚本中的参数进行调整。
+
+在诊断脚本内部,您将找到更多详细信息,甚至有关如何在SLURM环境中运行它的说明。
+
+另一种级别的调试是添加 `NCCL_DEBUG=INFO` 环境变量,如下所示:
+
+
+```bash
+NCCL_DEBUG=INFO python -m torch.distributed.run --nproc_per_node 2 --nnodes 1 torch-distributed-gpu-test.py
+```
+
+这将产生大量与NCCL相关的调试信息,如果发现有问题报告,您可以在线搜索以获取相关信息。或者,如果您不确定如何解释输出,可以在`issue`中分享日志文件。
+
+
+## 下溢和上溢检测
+
+
+
+目前,此功能仅适用于PyTorch。
+
+
+
+
+
+对于多GPU训练,它需要使用DDP(`torch.distributed.launch`)。
+
+
+
+
+
+此功能可以与任何基于`nn.Module`的模型一起使用。
+
+
+
+如果您开始发现`loss=NaN`或模型因激活值或权重中的`inf`或`nan`而出现一些异常行为,就需要发现第一个下溢或上溢发生的地方以及导致它的原因。幸运的是,您可以通过激活一个特殊模块来自动进行检测。
+
+如果您正在使用[`Trainer`],只需把以下内容:
+
+
+```bash
+--debug underflow_overflow
+```
+
+添加到常规命令行参数中,或在创建[`TrainingArguments`]对象时传递 `debug="underflow_overflow"`。
+
+如果您正在使用自己的训练循环或其他Trainer,您可以通过以下方式实现相同的功能:
+
+```python
+from transformers.debug_utils import DebugUnderflowOverflow
+
+debug_overflow = DebugUnderflowOverflow(model)
+```
+
+[`debug_utils.DebugUnderflowOverflow`] 将`hooks`插入模型,紧跟在每次前向调用之后,进而测试输入和输出变量,以及相应模块的权重。一旦在激活值或权重的至少一个元素中检测到`inf`或`nan`,程序将执行`assert`并打印报告,就像这样(这是在`google/mt5-small`下使用fp16混合精度捕获的):
+
+```
+Detected inf/nan during batch_number=0
+Last 21 forward frames:
+abs min abs max metadata
+ encoder.block.1.layer.1.DenseReluDense.dropout Dropout
+0.00e+00 2.57e+02 input[0]
+0.00e+00 2.85e+02 output
+[...]
+ encoder.block.2.layer.0 T5LayerSelfAttention
+6.78e-04 3.15e+03 input[0]
+2.65e-04 3.42e+03 output[0]
+ None output[1]
+2.25e-01 1.00e+04 output[2]
+ encoder.block.2.layer.1.layer_norm T5LayerNorm
+8.69e-02 4.18e-01 weight
+2.65e-04 3.42e+03 input[0]
+1.79e-06 4.65e+00 output
+ encoder.block.2.layer.1.DenseReluDense.wi_0 Linear
+2.17e-07 4.50e+00 weight
+1.79e-06 4.65e+00 input[0]
+2.68e-06 3.70e+01 output
+ encoder.block.2.layer.1.DenseReluDense.wi_1 Linear
+8.08e-07 2.66e+01 weight
+1.79e-06 4.65e+00 input[0]
+1.27e-04 2.37e+02 output
+ encoder.block.2.layer.1.DenseReluDense.dropout Dropout
+0.00e+00 8.76e+03 input[0]
+0.00e+00 9.74e+03 output
+ encoder.block.2.layer.1.DenseReluDense.wo Linear
+1.01e-06 6.44e+00 weight
+0.00e+00 9.74e+03 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.DenseReluDense T5DenseGatedGeluDense
+1.79e-06 4.65e+00 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.dropout Dropout
+3.18e-04 6.27e+04 input[0]
+0.00e+00 inf output
+```
+
+由于篇幅原因,示例输出中间的部分已经被缩减。
+
+第二列显示了绝对最大元素的值,因此,如果您仔细查看最后`frame`,输入和输出都在`1e4`的范围内。因此,在使用fp16混合精度进行训练时,最后一步发生了溢出(因为在`fp16`下,在`inf`之前的最大数字是`64e3`)。为了避免在`fp16`下发生溢出,激活值必须保持低于`1e4`,因为`1e4 * 1e4 = 1e8`,因此任何具有大激活值的矩阵乘法都会导致数值溢出。
+
+在跟踪的开始处,您可以发现问题发生在哪个批次(这里的`Detected inf/nan during batch_number=0`表示问题发生在第一个批次)。
+
+每个报告的`frame`都以声明相应模块的层信息为开头,说明这一`frame`是为哪个模块报告的。如果只看这个`frame`:
+
+```
+ encoder.block.2.layer.1.layer_norm T5LayerNorm
+8.69e-02 4.18e-01 weight
+2.65e-04 3.42e+03 input[0]
+1.79e-06 4.65e+00 output
+```
+
+在这里,`encoder.block.2.layer.1.layer_norm` 表示它是编码器的第二个块中第一层的`layer norm`。而 `forward` 的具体调用是 `T5LayerNorm`。
+
+让我们看看该报告的最后几个`frame`:
+
+```
+Detected inf/nan during batch_number=0
+Last 21 forward frames:
+abs min abs max metadata
+[...]
+ encoder.block.2.layer.1.DenseReluDense.wi_0 Linear
+2.17e-07 4.50e+00 weight
+1.79e-06 4.65e+00 input[0]
+2.68e-06 3.70e+01 output
+ encoder.block.2.layer.1.DenseReluDense.wi_1 Linear
+8.08e-07 2.66e+01 weight
+1.79e-06 4.65e+00 input[0]
+1.27e-04 2.37e+02 output
+ encoder.block.2.layer.1.DenseReluDense.wo Linear
+1.01e-06 6.44e+00 weight
+0.00e+00 9.74e+03 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.DenseReluDense T5DenseGatedGeluDense
+1.79e-06 4.65e+00 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.dropout Dropout
+3.18e-04 6.27e+04 input[0]
+0.00e+00 inf output
+```
+
+最后一个`frame`报告了`Dropout.forward`函数,第一个条目是唯一的输入,第二个条目是唯一的输出。您可以看到,它是从`DenseReluDense`类内的属性`dropout`中调用的。我们可以看到它发生在第2个块的第1层,也就是在第一个批次期间。最后,绝对最大的输入元素值为`6.27e+04`,输出也是`inf`。
+
+您可以在这里看到,`T5DenseGatedGeluDense.forward`产生了输出激活值,其绝对最大值约为62.7K,非常接近fp16的上限64K。在下一个`frame`中,我们有`Dropout`对权重进行重新归一化,之后将某些元素归零,将绝对最大值推到了64K以上,导致溢出(`inf`)。
+
+正如你所看到的,我们需要查看前面的`frame`, 从那里fp16数字开始变得非常大。
+
+让我们将报告与`models/t5/modeling_t5.py`中的代码匹配:
+
+```python
+class T5DenseGatedGeluDense(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.wi_0 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wi_1 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wo = nn.Linear(config.d_ff, config.d_model, bias=False)
+ self.dropout = nn.Dropout(config.dropout_rate)
+ self.gelu_act = ACT2FN["gelu_new"]
+
+ def forward(self, hidden_states):
+ hidden_gelu = self.gelu_act(self.wi_0(hidden_states))
+ hidden_linear = self.wi_1(hidden_states)
+ hidden_states = hidden_gelu * hidden_linear
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+```
+
+现在很容易看到`dropout`调用,以及所有之前的调用。
+
+由于检测是在前向`hook`中进行的,这些报告将立即在每个`forward`返回后打印出来。
+
+回到完整的报告,要采取措施并解决问题,我们需要往回看几个`frame`,在那里数字开始上升,并且最有可能切换到fp32模式以便在乘法或求和时数字不会溢出。当然,可能还有其他解决方案。例如,如果启用了`amp`,我们可以在将原始`forward`移到`helper wrapper`中后,暂时关闭它,如下所示:
+
+```python
+def _forward(self, hidden_states):
+ hidden_gelu = self.gelu_act(self.wi_0(hidden_states))
+ hidden_linear = self.wi_1(hidden_states)
+ hidden_states = hidden_gelu * hidden_linear
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+
+import torch
+
+
+def forward(self, hidden_states):
+ if torch.is_autocast_enabled():
+ with torch.cuda.amp.autocast(enabled=False):
+ return self._forward(hidden_states)
+ else:
+ return self._forward(hidden_states)
+```
+
+由于自动检测器仅报告完整`frame`的输入和输出,一旦知道在哪里查找,您可能还希望分析特定`forward`函数的中间阶段。在这种情况下,您可以使用`detect_overflow`辅助函数将检测器放到希望的位置,例如:
+
+```python
+from debug_utils import detect_overflow
+
+
+class T5LayerFF(nn.Module):
+ [...]
+
+ def forward(self, hidden_states):
+ forwarded_states = self.layer_norm(hidden_states)
+ detect_overflow(forwarded_states, "after layer_norm")
+ forwarded_states = self.DenseReluDense(forwarded_states)
+ detect_overflow(forwarded_states, "after DenseReluDense")
+ return hidden_states + self.dropout(forwarded_states)
+```
+
+可以看到,我们添加了2个检测器,现在我们可以跟踪是否在`forwarded_states`中间的某个地方检测到了`inf`或`nan`。
+
+实际上,检测器已经报告了这些,因为上面示例中的每个调用都是一个`nn.Module`,但假设如果您有一些本地的直接计算,这就是您将如何执行的方式。
+
+此外,如果您在自己的代码中实例化调试器,您可以调整从其默认打印的`frame`数,例如:
+
+```python
+from transformers.debug_utils import DebugUnderflowOverflow
+
+debug_overflow = DebugUnderflowOverflow(model, max_frames_to_save=100)
+```
+
+### 特定批次的绝对最小值和最大值跟踪
+
+当关闭下溢/上溢检测功能, 同样的调试类可以用于批处理跟踪。
+
+假设您想要监视给定批次的每个`forward`调用的所有成分的绝对最小值和最大值,并且仅对批次1和3执行此操作,您可以这样实例化这个类:
+
+```python
+debug_overflow = DebugUnderflowOverflow(model, trace_batch_nums=[1, 3])
+```
+
+现在,完整的批次1和3将以与下溢/上溢检测器相同的格式进行跟踪。
+
+批次从0开始计数。
+
+如果您知道程序在某个批次编号之后开始出现问题,那么您可以直接快进到该区域。以下是一个截取的配置示例输出:
+
+```
+ *** Starting batch number=1 ***
+abs min abs max metadata
+ shared Embedding
+1.01e-06 7.92e+02 weight
+0.00e+00 2.47e+04 input[0]
+5.36e-05 7.92e+02 output
+[...]
+ decoder.dropout Dropout
+1.60e-07 2.27e+01 input[0]
+0.00e+00 2.52e+01 output
+ decoder T5Stack
+ not a tensor output
+ lm_head Linear
+1.01e-06 7.92e+02 weight
+0.00e+00 1.11e+00 input[0]
+6.06e-02 8.39e+01 output
+ T5ForConditionalGeneration
+ not a tensor output
+
+ *** Starting batch number=3 ***
+abs min abs max metadata
+ shared Embedding
+1.01e-06 7.92e+02 weight
+0.00e+00 2.78e+04 input[0]
+5.36e-05 7.92e+02 output
+[...]
+```
+
+在这里,您将获得大量的`frame`被`dump` - 与您的模型中的前向调用一样多,它有可能符合也可能不符合您的要求,但有时对于调试目的来说,它可能比正常的调试器更容易使用。例如,如果问题开始发生在批次号150上,您可以`dump`批次149和150的跟踪,并比较数字开始发散的地方。
+
+你还可以使用以下命令指定停止训练的批次号:
+
+```python
+debug_overflow = DebugUnderflowOverflow(model, trace_batch_nums=[1, 3], abort_after_batch_num=3)
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/fast_tokenizers.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/fast_tokenizers.md
new file mode 100644
index 0000000000000000000000000000000000000000..dd311c3791cc70503fcc13018e753d0d24db65ca
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/fast_tokenizers.md
@@ -0,0 +1,67 @@
+
+
+# 使用 🤗 Tokenizers 中的分词器
+
+[`PreTrainedTokenizerFast`] 依赖于 [🤗 Tokenizers](https://huggingface.co/docs/tokenizers) 库。从 🤗 Tokenizers 库获得的分词器可以被轻松地加载到 🤗 Transformers 中。
+
+在了解具体内容之前,让我们先用几行代码创建一个虚拟的分词器:
+
+```python
+>>> from tokenizers import Tokenizer
+>>> from tokenizers.models import BPE
+>>> from tokenizers.trainers import BpeTrainer
+>>> from tokenizers.pre_tokenizers import Whitespace
+
+>>> tokenizer = Tokenizer(BPE(unk_token="[UNK]"))
+>>> trainer = BpeTrainer(special_tokens=["[UNK]", "[CLS]", "[SEP]", "[PAD]", "[MASK]"])
+
+>>> tokenizer.pre_tokenizer = Whitespace()
+>>> files = [...]
+>>> tokenizer.train(files, trainer)
+```
+
+现在,我们拥有了一个针对我们定义的文件进行训练的分词器。我们可以在当前运行时中继续使用它,或者将其保存到一个 JSON 文件以供将来重复使用。
+
+## 直接从分词器对象加载
+
+让我们看看如何利用 🤗 Transformers 库中的这个分词器对象。[`PreTrainedTokenizerFast`] 类允许通过接受已实例化的 *tokenizer* 对象作为参数,进行轻松实例化:
+
+```python
+>>> from transformers import PreTrainedTokenizerFast
+
+>>> fast_tokenizer = PreTrainedTokenizerFast(tokenizer_object=tokenizer)
+```
+
+现在可以使用这个对象,使用 🤗 Transformers 分词器共享的所有方法!前往[分词器页面](main_classes/tokenizer)了解更多信息。
+
+## 从 JSON 文件加载
+
+为了从 JSON 文件中加载分词器,让我们先保存我们的分词器:
+
+```python
+>>> tokenizer.save("tokenizer.json")
+```
+
+我们保存此文件的路径可以通过 `tokenizer_file` 参数传递给 [`PreTrainedTokenizerFast`] 初始化方法:
+
+```python
+>>> from transformers import PreTrainedTokenizerFast
+
+>>> fast_tokenizer = PreTrainedTokenizerFast(tokenizer_file="tokenizer.json")
+```
+
+现在可以使用这个对象,使用 🤗 Transformers 分词器共享的所有方法!前往[分词器页面](main_classes/tokenizer)了解更多信息。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/fsdp.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/fsdp.md
new file mode 100644
index 0000000000000000000000000000000000000000..4688b021f7416e27eeb921b9b28bb5c5eaa69046
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/fsdp.md
@@ -0,0 +1,161 @@
+
+
+# 完全分片数据并行
+
+[完全分片数据并行(FSDP)](https://pytorch.org/blog/introducing-pytorch-fully-sharded-data-parallel-api/)是一种数据并行方法,
+它将模型的参数、梯度和优化器状态在可用 GPU(也称为 Worker 或 *rank*)的数量上进行分片。
+与[分布式数据并行(DDP)](https://pytorch.org/docs/stable/generated/torch.nn.parallel.DistributedDataParallel.html)不同,
+FSDP 减少了内存使用量,因为模型在每个 GPU 上都被复制了一次。这就提高了 GPU 内存效率,
+使您能够用较少的 GPU 训练更大的模型。FSDP 已经集成到 Accelerate 中,
+这是一个用于在分布式环境中轻松管理训练的库,这意味着可以从 [`Trainer`] 类中调用这个库。
+
+在开始之前,请确保已安装 Accelerate,并且至少使用 PyTorch 2.1.0 或更高版本。
+
+```bash
+pip install accelerate
+```
+
+## FSDP 配置
+
+首先,运行 [`accelerate config`](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-config)
+命令为您的训练环境创建一个配置文件。Accelerate 使用此配置文件根据您在 `accelerate config`
+中选择的训练选项来自动搭建正确的训练环境。
+
+```bash
+accelerate config
+```
+
+运行 `accelerate config` 时,您将被提示一系列选项来配置训练环境。
+本节涵盖了一些最重要的 FSDP 选项。要了解有关其他可用的 FSDP 选项的更多信息,
+请查阅 [fsdp_config](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments.fsdp_config) 参数。
+
+### 分片策略
+
+FSDP 提供了多种可选择的分片策略:
+
+- `FULL_SHARD` - 将模型参数、梯度和优化器状态跨 Worker 进行分片;为此选项选择 `1`
+- `SHARD_GRAD_OP`- 将梯度和优化器状态跨 Worker 进行分片;为此选项选择 `2`
+- `NO_SHARD` - 不分片任何内容(这等同于 DDP);为此选项选择 `3`
+- `HYBRID_SHARD` - 在每个 Worker 中分片模型参数、梯度和优化器状态,其中每个 Worker 也有完整副本;为此选项选择 `4`
+- `HYBRID_SHARD_ZERO2` - 在每个 Worker 中分片梯度和优化器状态,其中每个 Worker 也有完整副本;为此选项选择 `5`
+
+这由 `fsdp_sharding_strategy` 标志启用。
+
+### CPU 卸载
+
+当参数和梯度在不使用时可以卸载到 CPU 上,以节省更多 GPU 内存并帮助您适应即使 FSDP 也不足以容纳大型模型的情况。
+在运行 `accelerate config` 时,通过设置 `fsdp_offload_params: true` 来启用此功能。
+
+### 包装策略
+
+FSDP 是通过包装网络中的每个层来应用的。通常,包装是以嵌套方式应用的,其中完整的权重在每次前向传递后被丢弃,
+以便在下一层使用内存。**自动包装**策略是实现这一点的最简单方法,您不需要更改任何代码。
+您应该选择 `fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP` 来包装一个 Transformer 层,
+并且 `fsdp_transformer_layer_cls_to_wrap` 来指定要包装的层(例如 `BertLayer`)。
+
+否则,您可以选择基于大小的包装策略,其中如果一层的参数超过一定数量,则应用 FSDP。通过设置
+`fsdp_wrap_policy: SIZE_BASED_WRAP` 和 `min_num_param` 来启用此功能,将参数设置为所需的大小阈值。
+
+### 检查点
+
+应该使用 `fsdp_state_dict_type: SHARDED_STATE_DICT` 来保存中间检查点,
+因为在排名 0 上保存完整状态字典需要很长时间,通常会导致 `NCCL Timeout` 错误,因为在广播过程中会无限期挂起。
+您可以使用 [`~accelerate.Accelerator.load_state`] 方法加载分片状态字典以恢复训练。
+
+```py
+# 包含检查点的目录
+accelerator.load_state("ckpt")
+```
+
+然而,当训练结束时,您希望保存完整状态字典,因为分片状态字典仅与 FSDP 兼容。
+
+```py
+if trainer.is_fsdp_enabled:
+ trainer.accelerator.state.fsdp_plugin.set_state_dict_type("FULL_STATE_DICT")
+
+trainer.save_model(script_args.output_dir)
+```
+
+### TPU
+
+[PyTorch XLA](https://pytorch.org/xla/release/2.1/index.html) 支持用于 TPUs 的 FSDP 训练,
+可以通过修改由 `accelerate config` 生成的 FSDP 配置文件来启用。除了上面指定的分片策略和包装选项外,
+您还可以将以下参数添加到文件中。
+
+```yaml
+xla: True # 必须设置为 True 以启用 PyTorch/XLA
+xla_fsdp_settings: # XLA 特定的 FSDP 参数
+xla_fsdp_grad_ckpt: True # 使用梯度检查点
+```
+
+[`xla_fsdp_settings`](https://github.com/pytorch/xla/blob/2e6e183e0724818f137c8135b34ef273dea33318/torch_xla/distributed/fsdp/xla_fully_sharded_data_parallel.py#L128)
+允许您配置用于 FSDP 的额外 XLA 特定参数。
+
+## 启动训练
+
+FSDP 配置文件示例如下所示:
+
+```yaml
+compute_environment: LOCAL_MACHINE
+debug: false
+distributed_type: FSDP
+downcast_bf16: "no"
+fsdp_config:
+ fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
+ fsdp_backward_prefetch_policy: BACKWARD_PRE
+ fsdp_cpu_ram_efficient_loading: true
+ fsdp_forward_prefetch: false
+ fsdp_offload_params: true
+ fsdp_sharding_strategy: 1
+ fsdp_state_dict_type: SHARDED_STATE_DICT
+ fsdp_sync_module_states: true
+ fsdp_transformer_layer_cls_to_wrap: BertLayer
+ fsdp_use_orig_params: true
+machine_rank: 0
+main_training_function: main
+mixed_precision: bf16
+num_machines: 1
+num_processes: 2
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+要启动训练,请运行 [`accelerate launch`](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-launch)
+命令,它将自动使用您之前使用 `accelerate config` 创建的配置文件。
+
+```bash
+accelerate launch my-trainer-script.py
+```
+
+```bash
+accelerate launch --fsdp="full shard" --fsdp_config="path/to/fsdp_config/ my-trainer-script.py
+```
+
+## 下一步
+
+FSDP 在大规模模型训练方面是一个强大的工具,您可以使用多个 GPU 或 TPU。
+通过分片模型参数、优化器和梯度状态,甚至在它们不活动时将其卸载到 CPU 上,
+FSDP 可以减少大规模训练的高成本。如果您希望了解更多信息,下面的内容可能会有所帮助:
+
+- 深入参考 Accelerate 指南,了解有关
+ [FSDP](https://huggingface.co/docs/accelerate/usage_guides/fsdp)的更多信息。
+- 阅读[介绍 PyTorch 完全分片数据并行(FSDP)API](https://pytorch.org/blog/introducing-pytorch-fully-sharded-data-parallel-api/) 博文。
+- 阅读[使用 FSDP 在云 TPU 上扩展 PyTorch 模型](https://pytorch.org/blog/scaling-pytorch-models-on-cloud-tpus-with-fsdp/)博文。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/gguf.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/gguf.md
new file mode 100644
index 0000000000000000000000000000000000000000..3da64a5d9956a18e185517e05ad754e502d08529
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/gguf.md
@@ -0,0 +1,104 @@
+
+
+# GGUF 和 Transformers 的交互
+
+GGUF文件格式用于存储模型,以便通过[GGML](https://github.com/ggerganov/ggml)和其他依赖它的库进行推理,例如非常流行的[llama.cpp](https://github.com/ggerganov/llama.cpp)或[whisper.cpp](https://github.com/ggerganov/whisper.cpp)。
+
+该文件格式[由抱抱脸支持](https://huggingface.co/docs/hub/en/gguf),可用于快速检查文件中张量和元数据。
+
+该文件格式是一种“单文件格式”,通常单个文件就包含了配置属性、分词器词汇表和其他属性,同时还有模型中要加载的所有张量。这些文件根据文件的量化类型有不同的格式。我们在[这里](https://huggingface.co/docs/hub/en/gguf#quantization-types)进行了简要介绍。
+
+## 在 Transformers 中的支持
+
+我们在 transformers 中添加了加载 gguf 文件的功能,这样可以对 GGUF 模型进行进一步的训练或微调,然后再将模型转换回 GGUF 格式,以便在 ggml 生态系统中使用。加载模型时,我们首先将其反量化为 FP32,然后再加载权重以在 PyTorch 中使用。
+
+> [!注意]
+> 目前这个功能还处于探索阶段,欢迎大家贡献力量,以便在不同量化类型和模型架构之间更好地完善这一功能。
+
+目前,支持的模型架构和量化类型如下:
+
+### 支持的量化类型
+
+根据分享在 Hub 上的较为热门的量化文件,初步支持以下量化类型:
+
+- F32
+- F16
+- BF16
+- Q4_0
+- Q4_1
+- Q5_0
+- Q5_1
+- Q8_0
+- Q2_K
+- Q3_K
+- Q4_K
+- Q5_K
+- Q6_K
+- IQ1_S
+- IQ1_M
+- IQ2_XXS
+- IQ2_XS
+- IQ2_S
+- IQ3_XXS
+- IQ3_S
+- IQ4_XS
+- IQ4_NL
+
+> [!注意]
+> 为了支持 gguf 反量化,需要安装 `gguf>=0.10.0`。
+
+### 支持的模型架构
+
+目前支持以下在 Hub 上非常热门的模型架构:
+
+- LLaMa
+- Mistral
+- Qwen2
+- Qwen2Moe
+- Phi3
+- Bloom
+- Falcon
+- StableLM
+- GPT2
+- Starcoder2
+
+## 使用示例
+
+为了在`transformers`中加载`gguf`文件,你需要在 `from_pretrained`方法中为分词器和模型指定 `gguf_file`参数。下面是从同一个文件中加载分词器和模型的示例:
+
+```py
+from transformers import AutoTokenizer, AutoModelForCausalLM
+
+model_id = "TheBloke/TinyLlama-1.1B-Chat-v1.0-GGUF"
+filename = "tinyllama-1.1b-chat-v1.0.Q6_K.gguf"
+
+tokenizer = AutoTokenizer.from_pretrained(model_id, gguf_file=filename)
+model = AutoModelForCausalLM.from_pretrained(model_id, gguf_file=filename)
+```
+
+现在,你就已经可以结合 PyTorch 生态系统中的一系列其他工具,来使用完整的、未量化的模型了。
+
+为了将模型转换回`gguf`文件,我们建议使用`llama.cpp`中的[`convert-hf-to-gguf.py`文件](https://github.com/ggerganov/llama.cpp/blob/master/convert_hf_to_gguf.py)。
+
+以下是如何补充上面的脚本,以保存模型并将其导出回 `gguf`的示例:
+
+```py
+tokenizer.save_pretrained('directory')
+model.save_pretrained('directory')
+
+!python ${path_to_llama_cpp}/convert-hf-to-gguf.py ${directory}
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/hpo_train.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/hpo_train.md
new file mode 100644
index 0000000000000000000000000000000000000000..907be0a21fa8ae2899e1e6b0bfe32b0aa8747135
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/hpo_train.md
@@ -0,0 +1,139 @@
+
+
+# 使用Trainer API进行超参数搜索
+
+🤗 Transformers库提供了一个优化过的[`Trainer`]类,用于训练🤗 Transformers模型,相比于手动编写自己的训练循环,这更容易开始训练。[`Trainer`]提供了超参数搜索的API。本文档展示了如何在示例中启用它。
+
+
+## 超参数搜索后端
+
+[`Trainer`] 目前支持四种超参数搜索后端:[optuna](https://optuna.org/),[sigopt](https://sigopt.com/),[raytune](https://docs.ray.io/en/latest/tune/index.html),[wandb](https://wandb.ai/site/sweeps)
+
+在使用它们之前,您应该先安装它们作为超参数搜索后端。
+
+```bash
+pip install optuna/sigopt/wandb/ray[tune]
+```
+
+## 如何在示例中启用超参数搜索
+
+定义超参数搜索空间,不同的后端需要不同的格式。
+
+对于sigopt,请参阅sigopt [object_parameter](https://docs.sigopt.com/ai-module-api-references/api_reference/objects/object_parameter),它类似于以下内容:
+
+```py
+>>> def sigopt_hp_space(trial):
+... return [
+... {"bounds": {"min": 1e-6, "max": 1e-4}, "name": "learning_rate", "type": "double"},
+... {
+... "categorical_values": ["16", "32", "64", "128"],
+... "name": "per_device_train_batch_size",
+... "type": "categorical",
+... },
+... ]
+```
+
+对于optuna,请参阅optuna [object_parameter](https://optuna.readthedocs.io/en/stable/tutorial/10_key_features/002_configurations.html#sphx-glr-tutorial-10-key-features-002-configurations-py),它类似于以下内容:
+
+```py
+>>> def optuna_hp_space(trial):
+... return {
+... "learning_rate": trial.suggest_float("learning_rate", 1e-6, 1e-4, log=True),
+... "per_device_train_batch_size": trial.suggest_categorical("per_device_train_batch_size", [16, 32, 64, 128]),
+... }
+```
+
+Optuna提供了多目标HPO。您可以在`hyperparameter_search`中传递`direction`参数,并定义自己的`compute_objective`以返回多个目标值。在`hyperparameter_search`中将返回Pareto Front(`List[BestRun]`),您应该参考[test_trainer](https://github.com/huggingface/transformers/blob/main/tests/trainer/test_trainer.py)中的测试用例`TrainerHyperParameterMultiObjectOptunaIntegrationTest`。它类似于以下内容:
+
+```py
+>>> best_trials = trainer.hyperparameter_search(
+... direction=["minimize", "maximize"],
+... backend="optuna",
+... hp_space=optuna_hp_space,
+... n_trials=20,
+... compute_objective=compute_objective,
+... )
+```
+
+对于raytune,可以参考raytune的[object_parameter](https://docs.ray.io/en/latest/tune/api/search_space.html),它类似于以下内容:
+
+```py
+>>> def ray_hp_space(trial):
+... return {
+... "learning_rate": tune.loguniform(1e-6, 1e-4),
+... "per_device_train_batch_size": tune.choice([16, 32, 64, 128]),
+... }
+```
+
+对于wandb,可以参考wandb的[object_parameter](https://docs.wandb.ai/guides/sweeps/configuration),它类似于以下内容:
+
+```py
+>>> def wandb_hp_space(trial):
+... return {
+... "method": "random",
+... "metric": {"name": "objective", "goal": "minimize"},
+... "parameters": {
+... "learning_rate": {"distribution": "uniform", "min": 1e-6, "max": 1e-4},
+... "per_device_train_batch_size": {"values": [16, 32, 64, 128]},
+... },
+... }
+```
+
+定义一个`model_init`函数并将其传递给[Trainer],作为示例:
+
+```py
+>>> def model_init(trial):
+... return AutoModelForSequenceClassification.from_pretrained(
+... model_args.model_name_or_path,
+... from_tf=bool(".ckpt" in model_args.model_name_or_path),
+... config=config,
+... cache_dir=model_args.cache_dir,
+... revision=model_args.model_revision,
+... use_auth_token=True if model_args.use_auth_token else None,
+... )
+```
+
+使用你的`model_init`函数、训练参数、训练和测试数据集以及评估函数创建一个[`Trainer`]。
+
+```py
+>>> trainer = Trainer(
+... model=None,
+... args=training_args,
+... train_dataset=small_train_dataset,
+... eval_dataset=small_eval_dataset,
+... compute_metrics=compute_metrics,
+... processing_class=tokenizer,
+... model_init=model_init,
+... data_collator=data_collator,
+... )
+```
+
+调用超参数搜索,获取最佳试验参数,后端可以是`"optuna"`/`"sigopt"`/`"wandb"`/`"ray"`。方向可以是`"minimize"`或`"maximize"`,表示是否优化更大或更低的目标。
+
+您可以定义自己的compute_objective函数,如果没有定义,将调用默认的compute_objective,并将评估指标(如f1)之和作为目标值返回。
+
+```py
+>>> best_trial = trainer.hyperparameter_search(
+... direction="maximize",
+... backend="optuna",
+... hp_space=optuna_hp_space,
+... n_trials=20,
+... compute_objective=compute_objective,
+... )
+```
+
+## 针对DDP微调的超参数搜索
+目前,Optuna和Sigopt已启用针对DDP的超参数搜索。只有rank-zero进程会进行超参数搜索并将参数传递给其他进程。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/index.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/index.md
new file mode 100644
index 0000000000000000000000000000000000000000..3750e506b0ea048032956cc537a575eb7f6879fc
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/index.md
@@ -0,0 +1,321 @@
+
+
+# 🤗 Transformers简介
+
+为 [PyTorch](https://pytorch.org/)、[TensorFlow](https://www.tensorflow.org/) 和 [JAX](https://jax.readthedocs.io/en/latest/) 打造的先进的机器学习工具.
+
+🤗 Transformers 提供了可以轻松地下载并且训练先进的预训练模型的 API 和工具。使用预训练模型可以减少计算消耗和碳排放,并且节省从头训练所需要的时间和资源。这些模型支持不同模态中的常见任务,比如:
+
+📝 **自然语言处理**:文本分类、命名实体识别、问答、语言建模、摘要、翻译、多项选择和文本生成。
+
+
+## 目录
+
+这篇文档由以下 5 个章节组成:
+
+- **开始使用** 包含了库的快速上手和安装说明,便于配置和运行。
+- **教程** 是一个初学者开始的好地方。本章节将帮助你获得你会用到的使用这个库的基本技能。
+- **操作指南** 向你展示如何实现一个特定目标,比如为语言建模微调一个预训练模型或者如何创造并分享个性化模型。
+- **概念指南** 对 🤗 Transformers 的模型,任务和设计理念背后的基本概念和思想做了更多的讨论和解释。
+- **API 介绍** 描述了所有的类和函数:
+
+ - **主要类别** 详述了配置(configuration)、模型(model)、分词器(tokenizer)和流水线(pipeline)这几个最重要的类。
+ - **模型** 详述了在这个库中和每个模型实现有关的类和函数。
+ - **内部帮助** 详述了内部使用的工具类和函数。
+
+### 支持的模型和框架
+
+下表展示了库中对每个模型的支持情况,如是否具有 Python 分词器(表中的“Tokenizer slow”)、是否具有由 🤗 Tokenizers 库支持的快速分词器(表中的“Tokenizer fast”)、是否支持 Jax(通过 Flax)、PyTorch 与 TensorFlow。
+
+
+
+| 模型 | PyTorch 支持 | TensorFlow 支持 | Flax 支持 |
+|:------------------------------------------------------------------------:|:---------------:|:------------------:|:------------:|
+| [ALBERT](../en/model_doc/albert.md) | ✅ | ✅ | ✅ |
+| [ALIGN](../en/model_doc/align.md) | ✅ | ❌ | ❌ |
+| [AltCLIP](../en/model_doc/altclip) | ✅ | ❌ | ❌ |
+| [Audio Spectrogram Transformer](../en/model_doc/audio-spectrogram-transformer) | ✅ | ❌ | ❌ |
+| [Autoformer](../en/model_doc/autoformer) | ✅ | ❌ | ❌ |
+| [Bark](../en/model_doc/bark) | ✅ | ❌ | ❌ |
+| [BART](../en/model_doc/bart) | ✅ | ✅ | ✅ |
+| [BARThez](../en/model_doc/barthez) | ✅ | ✅ | ✅ |
+| [BARTpho](../en/model_doc/bartpho) | ✅ | ✅ | ✅ |
+| [BEiT](../en/model_doc/beit) | ✅ | ❌ | ✅ |
+| [BERT](../en/model_doc/bert) | ✅ | ✅ | ✅ |
+| [Bert Generation](../en/model_doc/bert-generation) | ✅ | ❌ | ❌ |
+| [BertJapanese](../en/model_doc/bert-japanese) | ✅ | ✅ | ✅ |
+| [BERTweet](../en/model_doc/bertweet) | ✅ | ✅ | ✅ |
+| [BigBird](../en/model_doc/big_bird) | ✅ | ❌ | ✅ |
+| [BigBird-Pegasus](../en/model_doc/bigbird_pegasus) | ✅ | ❌ | ❌ |
+| [BioGpt](../en/model_doc/biogpt) | ✅ | ❌ | ❌ |
+| [BiT](../en/model_doc/bit) | ✅ | ❌ | ❌ |
+| [Blenderbot](../en/model_doc/blenderbot) | ✅ | ✅ | ✅ |
+| [BlenderbotSmall](../en/model_doc/blenderbot-small) | ✅ | ✅ | ✅ |
+| [BLIP](../en/model_doc/blip) | ✅ | ✅ | ❌ |
+| [BLIP-2](../en/model_doc/blip-2) | ✅ | ❌ | ❌ |
+| [BLOOM](../en/model_doc/bloom) | ✅ | ❌ | ✅ |
+| [BORT](../en/model_doc/bort) | ✅ | ✅ | ✅ |
+| [BridgeTower](../en/model_doc/bridgetower) | ✅ | ❌ | ❌ |
+| [BROS](../en/model_doc/bros) | ✅ | ❌ | ❌ |
+| [ByT5](../en/model_doc/byt5) | ✅ | ✅ | ✅ |
+| [CamemBERT](../en/model_doc/camembert) | ✅ | ✅ | ❌ |
+| [CANINE](../en/model_doc/canine) | ✅ | ❌ | ❌ |
+| [Chinese-CLIP](../en/model_doc/chinese_clip) | ✅ | ❌ | ❌ |
+| [CLAP](../en/model_doc/clap) | ✅ | ❌ | ❌ |
+| [CLIP](../en/model_doc/clip) | ✅ | ✅ | ✅ |
+| [CLIPSeg](../en/model_doc/clipseg) | ✅ | ❌ | ❌ |
+| [CLVP](../en/model_doc/clvp) | ✅ | ❌ | ❌ |
+| [CodeGen](../en/model_doc/codegen) | ✅ | ❌ | ❌ |
+| [CodeLlama](../en/model_doc/code_llama) | ✅ | ❌ | ✅ |
+| [Conditional DETR](../en/model_doc/conditional_detr) | ✅ | ❌ | ❌ |
+| [ConvBERT](../en/model_doc/convbert) | ✅ | ✅ | ❌ |
+| [ConvNeXT](../en/model_doc/convnext) | ✅ | ✅ | ❌ |
+| [ConvNeXTV2](../en/model_doc/convnextv2) | ✅ | ✅ | ❌ |
+| [CPM](../en/model_doc/cpm) | ✅ | ✅ | ✅ |
+| [CPM-Ant](../en/model_doc/cpmant) | ✅ | ❌ | ❌ |
+| [CTRL](../en/model_doc/ctrl) | ✅ | ✅ | ❌ |
+| [CvT](../en/model_doc/cvt) | ✅ | ✅ | ❌ |
+| [Data2VecAudio](../en/model_doc/data2vec) | ✅ | ❌ | ❌ |
+| [Data2VecText](../en/model_doc/data2vec) | ✅ | ❌ | ❌ |
+| [Data2VecVision](../en/model_doc/data2vec) | ✅ | ✅ | ❌ |
+| [DeBERTa](../en/model_doc/deberta) | ✅ | ✅ | ❌ |
+| [DeBERTa-v2](../en/model_doc/deberta-v2) | ✅ | ✅ | ❌ |
+| [Decision Transformer](../en/model_doc/decision_transformer) | ✅ | ❌ | ❌ |
+| [Deformable DETR](../en/model_doc/deformable_detr) | ✅ | ❌ | ❌ |
+| [DeiT](../en/model_doc/deit) | ✅ | ✅ | ❌ |
+| [DePlot](../en/model_doc/deplot) | ✅ | ❌ | ❌ |
+| [Depth Anything](../en/model_doc/depth_anything) | ✅ | ❌ | ❌ |
+| [DETA](../en/model_doc/deta) | ✅ | ❌ | ❌ |
+| [DETR](../en/model_doc/detr) | ✅ | ❌ | ❌ |
+| [DialoGPT](../en/model_doc/dialogpt) | ✅ | ✅ | ✅ |
+| [DiNAT](../en/model_doc/dinat) | ✅ | ❌ | ❌ |
+| [DINOv2](../en/model_doc/dinov2) | ✅ | ❌ | ❌ |
+| [DistilBERT](../en/model_doc/distilbert) | ✅ | ✅ | ✅ |
+| [DiT](../en/model_doc/dit) | ✅ | ❌ | ✅ |
+| [DonutSwin](../en/model_doc/donut) | ✅ | ❌ | ❌ |
+| [DPR](../en/model_doc/dpr) | ✅ | ✅ | ❌ |
+| [DPT](../en/model_doc/dpt) | ✅ | ❌ | ❌ |
+| [EfficientFormer](../en/model_doc/efficientformer) | ✅ | ✅ | ❌ |
+| [EfficientNet](../en/model_doc/efficientnet) | ✅ | ❌ | ❌ |
+| [ELECTRA](../en/model_doc/electra) | ✅ | ✅ | ✅ |
+| [EnCodec](../en/model_doc/encodec) | ✅ | ❌ | ❌ |
+| [Encoder decoder](../en/model_doc/encoder-decoder) | ✅ | ✅ | ✅ |
+| [ERNIE](../en/model_doc/ernie) | ✅ | ❌ | ❌ |
+| [ErnieM](../en/model_doc/ernie_m) | ✅ | ❌ | ❌ |
+| [ESM](../en/model_doc/esm) | ✅ | ✅ | ❌ |
+| [FairSeq Machine-Translation](../en/model_doc/fsmt) | ✅ | ❌ | ❌ |
+| [Falcon](../en/model_doc/falcon) | ✅ | ❌ | ❌ |
+| [FastSpeech2Conformer](../en/model_doc/fastspeech2_conformer) | ✅ | ❌ | ❌ |
+| [FLAN-T5](../en/model_doc/flan-t5) | ✅ | ✅ | ✅ |
+| [FLAN-UL2](../en/model_doc/flan-ul2) | ✅ | ✅ | ✅ |
+| [FlauBERT](../en/model_doc/flaubert) | ✅ | ✅ | ❌ |
+| [FLAVA](../en/model_doc/flava) | ✅ | ❌ | ❌ |
+| [FNet](../en/model_doc/fnet) | ✅ | ❌ | ❌ |
+| [FocalNet](../en/model_doc/focalnet) | ✅ | ❌ | ❌ |
+| [Funnel Transformer](../en/model_doc/funnel) | ✅ | ✅ | ❌ |
+| [Fuyu](../en/model_doc/fuyu) | ✅ | ❌ | ❌ |
+| [Gemma](../en/model_doc/gemma) | ✅ | ❌ | ✅ |
+| [GIT](../en/model_doc/git) | ✅ | ❌ | ❌ |
+| [GLPN](../en/model_doc/glpn) | ✅ | ❌ | ❌ |
+| [GPT Neo](../en/model_doc/gpt_neo) | ✅ | ❌ | ✅ |
+| [GPT NeoX](../en/model_doc/gpt_neox) | ✅ | ❌ | ❌ |
+| [GPT NeoX Japanese](../en/model_doc/gpt_neox_japanese) | ✅ | ❌ | ❌ |
+| [GPT-J](../en/model_doc/gptj) | ✅ | ✅ | ✅ |
+| [GPT-Sw3](../en/model_doc/gpt-sw3) | ✅ | ✅ | ✅ |
+| [GPTBigCode](../en/model_doc/gpt_bigcode) | ✅ | ❌ | ❌ |
+| [GPTSAN-japanese](../en/model_doc/gptsan-japanese) | ✅ | ❌ | ❌ |
+| [Graphormer](../en/model_doc/graphormer) | ✅ | ❌ | ❌ |
+| [GroupViT](../en/model_doc/groupvit) | ✅ | ✅ | ❌ |
+| [HerBERT](../en/model_doc/herbert) | ✅ | ✅ | ✅ |
+| [Hubert](../en/model_doc/hubert) | ✅ | ✅ | ❌ |
+| [I-BERT](../en/model_doc/ibert) | ✅ | ❌ | ❌ |
+| [IDEFICS](../en/model_doc/idefics) | ✅ | ❌ | ❌ |
+| [ImageGPT](../en/model_doc/imagegpt) | ✅ | ❌ | ❌ |
+| [Informer](../en/model_doc/informer) | ✅ | ❌ | ❌ |
+| [InstructBLIP](../en/model_doc/instructblip) | ✅ | ❌ | ❌ |
+| [Jukebox](../en/model_doc/jukebox) | ✅ | ❌ | ❌ |
+| [KOSMOS-2](../en/model_doc/kosmos-2) | ✅ | ❌ | ❌ |
+| [LayoutLM](../en/model_doc/layoutlm) | ✅ | ✅ | ❌ |
+| [LayoutLMv2](../en/model_doc/layoutlmv2) | ✅ | ❌ | ❌ |
+| [LayoutLMv3](../en/model_doc/layoutlmv3) | ✅ | ✅ | ❌ |
+| [LayoutXLM](../en/model_doc/layoutxlm) | ✅ | ❌ | ❌ |
+| [LED](../en/model_doc/led) | ✅ | ✅ | ❌ |
+| [LeViT](../en/model_doc/levit) | ✅ | ❌ | ❌ |
+| [LiLT](../en/model_doc/lilt) | ✅ | ❌ | ❌ |
+| [LLaMA](../en/model_doc/llama) | ✅ | ❌ | ✅ |
+| [Llama2](../en/model_doc/llama2) | ✅ | ❌ | ✅ |
+| [LLaVa](../en/model_doc/llava) | ✅ | ❌ | ❌ |
+| [Longformer](../en/model_doc/longformer) | ✅ | ✅ | ❌ |
+| [LongT5](../en/model_doc/longt5) | ✅ | ❌ | ✅ |
+| [LUKE](../en/model_doc/luke) | ✅ | ❌ | ❌ |
+| [LXMERT](../en/model_doc/lxmert) | ✅ | ✅ | ❌ |
+| [M-CTC-T](../en/model_doc/mctct) | ✅ | ❌ | ❌ |
+| [M2M100](../en/model_doc/m2m_100) | ✅ | ❌ | ❌ |
+| [MADLAD-400](../en/model_doc/madlad-400) | ✅ | ✅ | ✅ |
+| [Marian](../en/model_doc/marian) | ✅ | ✅ | ✅ |
+| [MarkupLM](../en/model_doc/markuplm) | ✅ | ❌ | ❌ |
+| [Mask2Former](../en/model_doc/mask2former) | ✅ | ❌ | ❌ |
+| [MaskFormer](../en/model_doc/maskformer) | ✅ | ❌ | ❌ |
+| [MatCha](../en/model_doc/matcha) | ✅ | ❌ | ❌ |
+| [mBART](../en/model_doc/mbart) | ✅ | ✅ | ✅ |
+| [mBART-50](../en/model_doc/mbart50) | ✅ | ✅ | ✅ |
+| [MEGA](../en/model_doc/mega) | ✅ | ❌ | ❌ |
+| [Megatron-BERT](../en/model_doc/megatron-bert) | ✅ | ❌ | ❌ |
+| [Megatron-GPT2](../en/model_doc/megatron_gpt2) | ✅ | ✅ | ✅ |
+| [MGP-STR](../en/model_doc/mgp-str) | ✅ | ❌ | ❌ |
+| [Mistral](../en/model_doc/mistral) | ✅ | ❌ | ✅ |
+| [Mixtral](../en/model_doc/mixtral) | ✅ | ❌ | ❌ |
+| [mLUKE](../en/model_doc/mluke) | ✅ | ❌ | ❌ |
+| [MMS](../en/model_doc/mms) | ✅ | ✅ | ✅ |
+| [MobileBERT](../en/model_doc/mobilebert) | ✅ | ✅ | ❌ |
+| [MobileNetV1](../en/model_doc/mobilenet_v1) | ✅ | ❌ | ❌ |
+| [MobileNetV2](../en/model_doc/mobilenet_v2) | ✅ | ❌ | ❌ |
+| [MobileViT](../en/model_doc/mobilevit) | ✅ | ✅ | ❌ |
+| [MobileViTV2](../en/model_doc/mobilevitv2) | ✅ | ❌ | ❌ |
+| [MPNet](../en/model_doc/mpnet) | ✅ | ✅ | ❌ |
+| [MPT](../en/model_doc/mpt) | ✅ | ❌ | ❌ |
+| [MRA](../en/model_doc/mra) | ✅ | ❌ | ❌ |
+| [MT5](../en/model_doc/mt5) | ✅ | ✅ | ✅ |
+| [MusicGen](../en/model_doc/musicgen) | ✅ | ❌ | ❌ |
+| [MVP](../en/model_doc/mvp) | ✅ | ❌ | ❌ |
+| [NAT](../en/model_doc/nat) | ✅ | ❌ | ❌ |
+| [Nezha](../en/model_doc/nezha) | ✅ | ❌ | ❌ |
+| [NLLB](../en/model_doc/nllb) | ✅ | ❌ | ❌ |
+| [NLLB-MOE](../en/model_doc/nllb-moe) | ✅ | ❌ | ❌ |
+| [Nougat](../en/model_doc/nougat) | ✅ | ✅ | ✅ |
+| [Nyströmformer](../en/model_doc/nystromformer) | ✅ | ❌ | ❌ |
+| [OneFormer](../en/model_doc/oneformer) | ✅ | ❌ | ❌ |
+| [OpenAI GPT](../en/model_doc/openai-gpt) | ✅ | ✅ | ❌ |
+| [OpenAI GPT-2](../en/model_doc/gpt2) | ✅ | ✅ | ✅ |
+| [OpenLlama](../en/model_doc/open-llama) | ✅ | ❌ | ❌ |
+| [OPT](../en/model_doc/opt) | ✅ | ✅ | ✅ |
+| [OWL-ViT](../en/model_doc/owlvit) | ✅ | ❌ | ❌ |
+| [OWLv2](../en/model_doc/owlv2) | ✅ | ❌ | ❌ |
+| [PatchTSMixer](../en/model_doc/patchtsmixer) | ✅ | ❌ | ❌ |
+| [PatchTST](../en/model_doc/patchtst) | ✅ | ❌ | ❌ |
+| [Pegasus](../en/model_doc/pegasus) | ✅ | ✅ | ✅ |
+| [PEGASUS-X](../en/model_doc/pegasus_x) | ✅ | ❌ | ❌ |
+| [Perceiver](../en/model_doc/perceiver) | ✅ | ❌ | ❌ |
+| [Persimmon](../en/model_doc/persimmon) | ✅ | ❌ | ❌ |
+| [Phi](../en/model_doc/phi) | ✅ | ❌ | ❌ |
+| [PhoBERT](../en/model_doc/phobert) | ✅ | ✅ | ✅ |
+| [Pix2Struct](../en/model_doc/pix2struct) | ✅ | ❌ | ❌ |
+| [PLBart](../en/model_doc/plbart) | ✅ | ❌ | ❌ |
+| [PoolFormer](../en/model_doc/poolformer) | ✅ | ❌ | ❌ |
+| [Pop2Piano](../en/model_doc/pop2piano) | ✅ | ❌ | ❌ |
+| [ProphetNet](../en/model_doc/prophetnet) | ✅ | ❌ | ❌ |
+| [PVT](../en/model_doc/pvt) | ✅ | ❌ | ❌ |
+| [QDQBert](../en/model_doc/qdqbert) | ✅ | ❌ | ❌ |
+| [Qwen2](../en/model_doc/qwen2) | ✅ | ❌ | ❌ |
+| [RAG](../en/model_doc/rag) | ✅ | ✅ | ❌ |
+| [REALM](../en/model_doc/realm) | ✅ | ❌ | ❌ |
+| [Reformer](../en/model_doc/reformer) | ✅ | ❌ | ❌ |
+| [RegNet](../en/model_doc/regnet) | ✅ | ✅ | ✅ |
+| [RemBERT](../en/model_doc/rembert) | ✅ | ✅ | ❌ |
+| [ResNet](../en/model_doc/resnet) | ✅ | ✅ | ✅ |
+| [RetriBERT](../en/model_doc/retribert) | ✅ | ❌ | ❌ |
+| [RoBERTa](../en/model_doc/roberta) | ✅ | ✅ | ✅ |
+| [RoBERTa-PreLayerNorm](../en/model_doc/roberta-prelayernorm) | ✅ | ✅ | ✅ |
+| [RoCBert](../en/model_doc/roc_bert) | ✅ | ❌ | ❌ |
+| [RoFormer](../en/model_doc/roformer) | ✅ | ✅ | ✅ |
+| [RWKV](../en/model_doc/rwkv) | ✅ | ❌ | ❌ |
+| [SAM](../en/model_doc/sam) | ✅ | ✅ | ❌ |
+| [SeamlessM4T](../en/model_doc/seamless_m4t) | ✅ | ❌ | ❌ |
+| [SeamlessM4Tv2](../en/model_doc/seamless_m4t_v2) | ✅ | ❌ | ❌ |
+| [SegFormer](../en/model_doc/segformer) | ✅ | ✅ | ❌ |
+| [SegGPT](../en/model_doc/seggpt) | ✅ | ❌ | ❌ |
+| [SEW](../en/model_doc/sew) | ✅ | ❌ | ❌ |
+| [SEW-D](../en/model_doc/sew-d) | ✅ | ❌ | ❌ |
+| [SigLIP](../en/model_doc/siglip) | ✅ | ❌ | ❌ |
+| [Speech Encoder decoder](../en/model_doc/speech-encoder-decoder) | ✅ | ❌ | ✅ |
+| [Speech2Text](../en/model_doc/speech_to_text) | ✅ | ✅ | ❌ |
+| [SpeechT5](../en/model_doc/speecht5) | ✅ | ❌ | ❌ |
+| [Splinter](../en/model_doc/splinter) | ✅ | ❌ | ❌ |
+| [SqueezeBERT](../en/model_doc/squeezebert) | ✅ | ❌ | ❌ |
+| [StableLm](../en/model_doc/stablelm) | ✅ | ❌ | ❌ |
+| [Starcoder2](../en/model_doc/starcoder2) | ✅ | ❌ | ❌ |
+| [SwiftFormer](../en/model_doc/swiftformer) | ✅ | ❌ | ❌ |
+| [Swin Transformer](../en/model_doc/swin) | ✅ | ✅ | ❌ |
+| [Swin Transformer V2](../en/model_doc/swinv2) | ✅ | ❌ | ❌ |
+| [Swin2SR](../en/model_doc/swin2sr) | ✅ | ❌ | ❌ |
+| [SwitchTransformers](../en/model_doc/switch_transformers) | ✅ | ❌ | ❌ |
+| [T5](../en/model_doc/t5) | ✅ | ✅ | ✅ |
+| [T5v1.1](../en/model_doc/t5v1.1) | ✅ | ✅ | ✅ |
+| [Table Transformer](../en/model_doc/table-transformer) | ✅ | ❌ | ❌ |
+| [TAPAS](../en/model_doc/tapas) | ✅ | ✅ | ❌ |
+| [TAPEX](../en/model_doc/tapex) | ✅ | ✅ | ✅ |
+| [Time Series Transformer](../en/model_doc/time_series_transformer) | ✅ | ❌ | ❌ |
+| [TimeSformer](../en/model_doc/timesformer) | ✅ | ❌ | ❌ |
+| [Trajectory Transformer](../en/model_doc/trajectory_transformer) | ✅ | ❌ | ❌ |
+| [Transformer-XL](../en/model_doc/transfo-xl) | ✅ | ✅ | ❌ |
+| [TrOCR](../en/model_doc/trocr) | ✅ | ❌ | ❌ |
+| [TVLT](../en/model_doc/tvlt) | ✅ | ❌ | ❌ |
+| [TVP](../en/model_doc/tvp) | ✅ | ❌ | ❌ |
+| [UL2](../en/model_doc/ul2) | ✅ | ✅ | ✅ |
+| [UMT5](../en/model_doc/umt5) | ✅ | ❌ | ❌ |
+| [UniSpeech](../en/model_doc/unispeech) | ✅ | ❌ | ❌ |
+| [UniSpeechSat](../en/model_doc/unispeech-sat) | ✅ | ❌ | ❌ |
+| [UnivNet](../en/model_doc/univnet) | ✅ | ❌ | ❌ |
+| [UPerNet](../en/model_doc/upernet) | ✅ | ❌ | ❌ |
+| [VAN](../en/model_doc/van) | ✅ | ❌ | ❌ |
+| [VideoMAE](../en/model_doc/videomae) | ✅ | ❌ | ❌ |
+| [ViLT](../en/model_doc/vilt) | ✅ | ❌ | ❌ |
+| [VipLlava](../en/model_doc/vipllava) | ✅ | ❌ | ❌ |
+| [Vision Encoder decoder](../en/model_doc/vision-encoder-decoder) | ✅ | ✅ | ✅ |
+| [VisionTextDualEncoder](../en/model_doc/vision-text-dual-encoder) | ✅ | ✅ | ✅ |
+| [VisualBERT](../en/model_doc/visual_bert) | ✅ | ❌ | ❌ |
+| [ViT](../en/model_doc/vit) | ✅ | ✅ | ✅ |
+| [ViT Hybrid](../en/model_doc/vit_hybrid) | ✅ | ❌ | ❌ |
+| [VitDet](../en/model_doc/vitdet) | ✅ | ❌ | ❌ |
+| [ViTMAE](../en/model_doc/vit_mae) | ✅ | ✅ | ❌ |
+| [ViTMatte](../en/model_doc/vitmatte) | ✅ | ❌ | ❌ |
+| [ViTMSN](../en/model_doc/vit_msn) | ✅ | ❌ | ❌ |
+| [VITS](../en/model_doc/vits) | ✅ | ❌ | ❌ |
+| [ViViT](../en/model_doc/vivit) | ✅ | ❌ | ❌ |
+| [Wav2Vec2](../en/model_doc/wav2vec2) | ✅ | ✅ | ✅ |
+| [Wav2Vec2-BERT](../en/model_doc/wav2vec2-bert) | ✅ | ❌ | ❌ |
+| [Wav2Vec2-Conformer](../en/model_doc/wav2vec2-conformer) | ✅ | ❌ | ❌ |
+| [Wav2Vec2Phoneme](../en/model_doc/wav2vec2_phoneme) | ✅ | ✅ | ✅ |
+| [WavLM](../en/model_doc/wavlm) | ✅ | ❌ | ❌ |
+| [Whisper](../en/model_doc/whisper) | ✅ | ✅ | ✅ |
+| [X-CLIP](../en/model_doc/xclip) | ✅ | ❌ | ❌ |
+| [X-MOD](../en/model_doc/xmod) | ✅ | ❌ | ❌ |
+| [XGLM](../en/model_doc/xglm) | ✅ | ✅ | ✅ |
+| [XLM](../en/model_doc/xlm) | ✅ | ✅ | ❌ |
+| [XLM-ProphetNet](../en/model_doc/xlm-prophetnet) | ✅ | ❌ | ❌ |
+| [XLM-RoBERTa](../en/model_doc/xlm-roberta) | ✅ | ✅ | ✅ |
+| [XLM-RoBERTa-XL](../en/model_doc/xlm-roberta-xl) | ✅ | ❌ | ❌ |
+| [XLM-V](../en/model_doc/xlm-v) | ✅ | ✅ | ✅ |
+| [XLNet](../en/model_doc/xlnet) | ✅ | ✅ | ❌ |
+| [XLS-R](../en/model_doc/xls_r) | ✅ | ✅ | ✅ |
+| [XLSR-Wav2Vec2](../en/model_doc/xlsr_wav2vec2) | ✅ | ✅ | ✅ |
+| [YOLOS](../en/model_doc/yolos) | ✅ | ❌ | ❌ |
+| [YOSO](../en/model_doc/yoso) | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/installation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/installation.md
new file mode 100644
index 0000000000000000000000000000000000000000..a9102f3393a740a988d88be496b6835e03575d57
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/installation.md
@@ -0,0 +1,256 @@
+
+
+# 安装
+
+为你正在使用的深度学习框架安装 🤗 Transformers、设置缓存,并选择性配置 🤗 Transformers 以离线运行。
+
+🤗 Transformers 已在 Python 3.6+、PyTorch 1.1.0+、TensorFlow 2.0+ 以及 Flax 上进行测试。针对你使用的深度学习框架,请参照以下安装说明进行安装:
+
+* [PyTorch](https://pytorch.org/get-started/locally/) 安装说明。
+* [TensorFlow 2.0](https://www.tensorflow.org/install/pip) 安装说明。
+* [Flax](https://flax.readthedocs.io/en/latest/) 安装说明。
+
+## 使用 pip 安装
+
+你应该使用 [虚拟环境](https://docs.python.org/3/library/venv.html) 安装 🤗 Transformers。如果你不熟悉 Python 虚拟环境,请查看此 [教程](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/)。使用虚拟环境,你可以轻松管理不同项目,避免不同依赖项之间的兼容性问题。
+
+首先,在项目目录中创建虚拟环境:
+
+```bash
+python -m venv .env
+```
+
+在 Linux 和 MacOs 系统中激活虚拟环境:
+
+```bash
+source .env/bin/activate
+```
+在 Windows 系统中激活虚拟环境:
+
+```bash
+.env/Scripts/activate
+```
+
+现在你可以使用以下命令安装 🤗 Transformers:
+
+```bash
+pip install transformers
+```
+
+若仅需 CPU 支持,可以使用单行命令方便地安装 🤗 Transformers 和深度学习库。例如,使用以下命令安装 🤗 Transformers 和 PyTorch:
+
+```bash
+pip install 'transformers[torch]'
+```
+
+🤗 Transformers 和 TensorFlow 2.0:
+
+```bash
+pip install 'transformers[tf-cpu]'
+```
+
+
+
+M1 / ARM用户
+
+在安装 TensorFlow 2.0 前,你需要安装以下库:
+```bash
+brew install cmake
+brew install pkg-config
+```
+
+
+
+🤗 Transformers 和 Flax:
+
+```bash
+pip install 'transformers[flax]'
+```
+
+最后,运行以下命令以检查 🤗 Transformers 是否已被正确安装。该命令将下载一个预训练模型:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('we love you'))"
+```
+
+然后打印标签以及分数:
+
+```bash
+[{'label': 'POSITIVE', 'score': 0.9998704791069031}]
+```
+
+## 源码安装
+
+使用以下命令从源码安装 🤗 Transformers:
+
+```bash
+pip install git+https://github.com/huggingface/transformers
+```
+
+此命令下载的是最新的前沿 `main` 版本而不是最新的 `stable` 版本。`main` 版本适用于跟最新开发保持一致。例如,上次正式版发布带来的 bug 被修复了,但新版本尚未被推出。但是,这也说明 `main` 版本并不一定总是稳定的。我们努力保持 `main` 版本的可操作性,大多数问题通常在几个小时或一天以内就能被解决。如果你遇到问题,请提个 [Issue](https://github.com/huggingface/transformers/issues) 以便我们能更快修复。
+
+运行以下命令以检查 🤗 Transformers 是否已被正确安装:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('I love you'))"
+```
+
+## 可编辑安装
+
+如果你有下列需求,需要进行可编辑安装:
+
+* 使用源码的 `main` 版本。
+* 为 🤗 Transformers 贡献代码,需要测试代码中的更改。
+
+使用以下命令克隆仓库并安装 🤗 Transformers:
+
+```bash
+git clone https://github.com/huggingface/transformers.git
+cd transformers
+pip install -e .
+```
+
+这些命令将会链接你克隆的仓库以及你的 Python 库路径。现在,Python 不仅会在正常的库路径中搜索库,也会在你克隆到的文件夹中进行查找。例如,如果你的 Python 包通常本应安装在 `~/anaconda3/envs/main/lib/python3.7/site-packages/` 目录中,在这种情况下 Python 也会搜索你克隆到的文件夹:`~/transformers/`。
+
+
+
+如果你想继续使用这个库,必须保留 `transformers` 文件夹。
+
+
+
+现在,你可以使用以下命令,将你克隆的 🤗 Transformers 库轻松更新至最新版本:
+
+```bash
+cd ~/transformers/
+git pull
+```
+
+你的 Python 环境将在下次运行时找到 `main` 版本的 🤗 Transformers。
+
+## 使用 conda 安装
+
+从 conda 的 `conda-forge` 频道安装:
+
+```bash
+conda install conda-forge::transformers
+```
+
+## 缓存设置
+
+预训练模型会被下载并本地缓存到 `~/.cache/huggingface/hub`。这是由环境变量 `TRANSFORMERS_CACHE` 指定的默认目录。在 Windows 上,默认目录为 `C:\Users\username\.cache\huggingface\hub`。你可以按照不同优先级改变下述环境变量,以指定不同的缓存目录。
+
+1. 环境变量(默认): `HF_HUB_CACHE` 或 `TRANSFORMERS_CACHE`。
+2. 环境变量 `HF_HOME`。
+3. 环境变量 `XDG_CACHE_HOME` + `/huggingface`。
+
+
+
+除非你明确指定了环境变量 `TRANSFORMERS_CACHE`,🤗 Transformers 将可能会使用较早版本设置的环境变量 `PYTORCH_TRANSFORMERS_CACHE` 或 `PYTORCH_PRETRAINED_BERT_CACHE`。
+
+
+
+## 离线模式
+
+🤗 Transformers 可以仅使用本地文件在防火墙或离线环境中运行。设置环境变量 `HF_HUB_OFFLINE=1` 以启用该行为。
+
+
+
+通过设置环境变量 `HF_DATASETS_OFFLINE=1` 将 [🤗 Datasets](https://huggingface.co/docs/datasets/) 添加至你的离线训练工作流程中。
+
+
+
+例如,你通常会使用以下命令对外部实例进行防火墙保护的的普通网络上运行程序:
+
+```bash
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+在离线环境中运行相同的程序:
+
+```bash
+HF_DATASETS_OFFLINE=1 HF_HUB_OFFLINE=1 \
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+现在脚本可以应该正常运行,而无需挂起或等待超时,因为它知道只应查找本地文件。
+
+### 获取离线时使用的模型和分词器
+
+另一种离线时使用 🤗 Transformers 的方法是预先下载好文件,然后在需要离线使用时指向它们的离线路径。有三种实现的方法:
+
+* 单击 [Model Hub](https://huggingface.co/models) 用户界面上的 ↓ 图标下载文件。
+
+ 
+
+* 使用 [`PreTrainedModel.from_pretrained`] 和 [`PreTrainedModel.save_pretrained`] 工作流程:
+
+ 1. 预先使用 [`PreTrainedModel.from_pretrained`] 下载文件:
+
+ ```py
+ >>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("bigscience/T0_3B")
+ >>> model = AutoModelForSeq2SeqLM.from_pretrained("bigscience/T0_3B")
+ ```
+
+ 2. 使用 [`PreTrainedModel.save_pretrained`] 将文件保存至指定目录:
+
+ ```py
+ >>> tokenizer.save_pretrained("./your/path/bigscience_t0")
+ >>> model.save_pretrained("./your/path/bigscience_t0")
+ ```
+
+ 3. 现在,你可以在离线时从指定目录使用 [`PreTrainedModel.from_pretrained`] 重新加载你的文件:
+
+ ```py
+ >>> tokenizer = AutoTokenizer.from_pretrained("./your/path/bigscience_t0")
+ >>> model = AutoModel.from_pretrained("./your/path/bigscience_t0")
+ ```
+
+* 使用代码用 [huggingface_hub](https://github.com/huggingface/huggingface_hub/tree/main/src/huggingface_hub) 库下载文件:
+
+ 1. 在你的虚拟环境中安装 `huggingface_hub` 库:
+
+ ```bash
+ python -m pip install huggingface_hub
+ ```
+
+ 2. 使用 [`hf_hub_download`](https://huggingface.co/docs/hub/adding-a-library#download-files-from-the-hub) 函数将文件下载到指定路径。例如,以下命令将 `config.json` 文件从 [T0](https://huggingface.co/bigscience/T0_3B) 模型下载至你想要的路径:
+
+ ```py
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> hf_hub_download(repo_id="bigscience/T0_3B", filename="config.json", cache_dir="./your/path/bigscience_t0")
+ ```
+
+下载完文件并在本地缓存后,指定其本地路径以加载和使用该模型:
+
+```py
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("./your/path/bigscience_t0/config.json")
+```
+
+
+
+请参阅 [如何从 Hub 下载文件](https://huggingface.co/docs/hub/how-to-downstream) 部分,获取有关下载存储在 Hub 上文件的更多详细信息。
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/audio_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/audio_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..17fc430f984287775dfa581d2e69902b3d484c96
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/audio_utils.md
@@ -0,0 +1,40 @@
+
+
+# `FeatureExtractors`的工具
+
+此页面列出了音频 [`FeatureExtractor`] 可以使用的所有实用函数,以便使用常见的算法(如 *Short Time Fourier Transform* 或 *log mel spectrogram*)从原始音频中计算特殊特征。
+
+其中大多数仅在您研究库中音频processors的代码时有用。
+
+
+## 音频转换
+
+[[autodoc]] audio_utils.hertz_to_mel
+
+[[autodoc]] audio_utils.mel_to_hertz
+
+[[autodoc]] audio_utils.mel_filter_bank
+
+[[autodoc]] audio_utils.optimal_fft_length
+
+[[autodoc]] audio_utils.window_function
+
+[[autodoc]] audio_utils.spectrogram
+
+[[autodoc]] audio_utils.power_to_db
+
+[[autodoc]] audio_utils.amplitude_to_db
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/file_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/file_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..ba4b4902814a65817e100afb87184a4cd152ff2d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/file_utils.md
@@ -0,0 +1,50 @@
+
+
+# 通用工具
+
+此页面列出了在`utils.py`文件中找到的所有Transformers通用实用函数。
+
+其中大多数仅在您研究库中的通用代码时才有用。
+
+
+## Enums和namedtuples(命名元组)
+
+[[autodoc]] utils.ExplicitEnum
+
+[[autodoc]] utils.PaddingStrategy
+
+[[autodoc]] utils.TensorType
+
+## 特殊的装饰函数
+
+[[autodoc]] utils.add_start_docstrings
+
+[[autodoc]] utils.add_start_docstrings_to_model_forward
+
+[[autodoc]] utils.add_end_docstrings
+
+[[autodoc]] utils.add_code_sample_docstrings
+
+[[autodoc]] utils.replace_return_docstrings
+
+## 特殊的属性
+
+[[autodoc]] utils.cached_property
+
+## 其他实用程序
+
+[[autodoc]] utils._LazyModule
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/generation_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/generation_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..084e2a29dc8cfca962b42eeca26e7de33d9f2e28
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/generation_utils.md
@@ -0,0 +1,331 @@
+
+
+# 用于生成的工具
+
+此页面列出了所有由 [`~generation.GenerationMixin.generate`]。
+
+## 生成输出
+
+[`~generation.GenerationMixin.generate`] 的输出是 [`~utils.ModelOutput`] 的一个子类的实例。这个输出是一种包含 [`~generation.GenerationMixin.generate`] 返回的所有信息数据结构,但也可以作为元组或字典使用。
+这里是一个例子:
+
+
+```python
+from transformers import GPT2Tokenizer, GPT2LMHeadModel
+
+tokenizer = GPT2Tokenizer.from_pretrained("openai-community/gpt2")
+model = GPT2LMHeadModel.from_pretrained("openai-community/gpt2")
+
+inputs = tokenizer("Hello, my dog is cute and ", return_tensors="pt")
+generation_output = model.generate(**inputs, return_dict_in_generate=True, output_scores=True)
+```
+
+`generation_output` 的对象是 [`~generation.GenerateDecoderOnlyOutput`] 的一个实例,从该类的文档中我们可以看到,这意味着它具有以下属性:
+
+- `sequences`: 生成的tokens序列
+- `scores`(可选): 每个生成步骤的语言建模头的预测分数
+- `hidden_states`(可选): 每个生成步骤模型的hidden states
+- `attentions`(可选): 每个生成步骤模型的注意力权重
+
+在这里,由于我们传递了 `output_scores=True`,我们具有 `scores` 属性。但我们没有 `hidden_states` 和 `attentions`,因为没有传递 `output_hidden_states=True` 或 `output_attentions=True`。
+
+您可以像通常一样访问每个属性,如果该属性未被模型返回,则将获得 `None`。例如,在这里 `generation_output.scores` 是语言建模头的所有生成预测分数,而 `generation_output.attentions` 为 `None`。
+
+当我们将 `generation_output` 对象用作元组时,它只保留非 `None` 值的属性。例如,在这里它有两个元素,`loss` 然后是 `logits`,所以
+
+
+```python
+generation_output[:2]
+```
+
+将返回元组`(generation_output.sequences, generation_output.scores)`。
+
+当我们将`generation_output`对象用作字典时,它只保留非`None`的属性。例如,它有两个键,分别是`sequences`和`scores`。
+
+我们在此记录所有输出类型。
+
+
+### PyTorch
+
+[[autodoc]] generation.GenerateDecoderOnlyOutput
+
+[[autodoc]] generation.GenerateEncoderDecoderOutput
+
+[[autodoc]] generation.GenerateBeamDecoderOnlyOutput
+
+[[autodoc]] generation.GenerateBeamEncoderDecoderOutput
+
+### TensorFlow
+
+[[autodoc]] generation.TFGreedySearchEncoderDecoderOutput
+
+[[autodoc]] generation.TFGreedySearchDecoderOnlyOutput
+
+[[autodoc]] generation.TFSampleEncoderDecoderOutput
+
+[[autodoc]] generation.TFSampleDecoderOnlyOutput
+
+[[autodoc]] generation.TFBeamSearchEncoderDecoderOutput
+
+[[autodoc]] generation.TFBeamSearchDecoderOnlyOutput
+
+[[autodoc]] generation.TFBeamSampleEncoderDecoderOutput
+
+[[autodoc]] generation.TFBeamSampleDecoderOnlyOutput
+
+[[autodoc]] generation.TFContrastiveSearchEncoderDecoderOutput
+
+[[autodoc]] generation.TFContrastiveSearchDecoderOnlyOutput
+
+### FLAX
+
+[[autodoc]] generation.FlaxSampleOutput
+
+[[autodoc]] generation.FlaxGreedySearchOutput
+
+[[autodoc]] generation.FlaxBeamSearchOutput
+
+## LogitsProcessor
+
+[`LogitsProcessor`] 可以用于修改语言模型头的预测分数以进行生成
+
+
+### PyTorch
+
+[[autodoc]] AlternatingCodebooksLogitsProcessor
+ - __call__
+
+[[autodoc]] ClassifierFreeGuidanceLogitsProcessor
+ - __call__
+
+[[autodoc]] EncoderNoRepeatNGramLogitsProcessor
+ - __call__
+
+[[autodoc]] EncoderRepetitionPenaltyLogitsProcessor
+ - __call__
+
+[[autodoc]] EpsilonLogitsWarper
+ - __call__
+
+[[autodoc]] EtaLogitsWarper
+ - __call__
+
+[[autodoc]] ExponentialDecayLengthPenalty
+ - __call__
+
+[[autodoc]] ForcedBOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] ForcedEOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] HammingDiversityLogitsProcessor
+ - __call__
+
+[[autodoc]] InfNanRemoveLogitsProcessor
+ - __call__
+
+[[autodoc]] LogitNormalization
+ - __call__
+
+[[autodoc]] LogitsProcessor
+ - __call__
+
+[[autodoc]] LogitsProcessorList
+ - __call__
+
+[[autodoc]] MinLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] MinNewTokensLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] NoBadWordsLogitsProcessor
+ - __call__
+
+[[autodoc]] NoRepeatNGramLogitsProcessor
+ - __call__
+
+[[autodoc]] PrefixConstrainedLogitsProcessor
+ - __call__
+
+[[autodoc]] RepetitionPenaltyLogitsProcessor
+ - __call__
+
+[[autodoc]] SequenceBiasLogitsProcessor
+ - __call__
+
+[[autodoc]] SuppressTokensAtBeginLogitsProcessor
+ - __call__
+
+[[autodoc]] SuppressTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] TemperatureLogitsWarper
+ - __call__
+
+[[autodoc]] TopKLogitsWarper
+ - __call__
+
+[[autodoc]] TopPLogitsWarper
+ - __call__
+
+[[autodoc]] TypicalLogitsWarper
+ - __call__
+
+[[autodoc]] UnbatchedClassifierFreeGuidanceLogitsProcessor
+ - __call__
+
+[[autodoc]] WhisperTimeStampLogitsProcessor
+ - __call__
+
+### TensorFlow
+
+[[autodoc]] TFForcedBOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] TFForcedEOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] TFForceTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] TFLogitsProcessor
+ - __call__
+
+[[autodoc]] TFLogitsProcessorList
+ - __call__
+
+[[autodoc]] TFLogitsWarper
+ - __call__
+
+[[autodoc]] TFMinLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] TFNoBadWordsLogitsProcessor
+ - __call__
+
+[[autodoc]] TFNoRepeatNGramLogitsProcessor
+ - __call__
+
+[[autodoc]] TFRepetitionPenaltyLogitsProcessor
+ - __call__
+
+[[autodoc]] TFSuppressTokensAtBeginLogitsProcessor
+ - __call__
+
+[[autodoc]] TFSuppressTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] TFTemperatureLogitsWarper
+ - __call__
+
+[[autodoc]] TFTopKLogitsWarper
+ - __call__
+
+[[autodoc]] TFTopPLogitsWarper
+ - __call__
+
+### FLAX
+
+[[autodoc]] FlaxForcedBOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxForcedEOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxForceTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxLogitsProcessorList
+ - __call__
+
+[[autodoc]] FlaxLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxMinLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxSuppressTokensAtBeginLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxSuppressTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxTemperatureLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxTopKLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxTopPLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxWhisperTimeStampLogitsProcessor
+ - __call__
+
+## StoppingCriteria
+
+可以使用[`StoppingCriteria`]来更改停止生成的时间(除了EOS token以外的方法)。请注意,这仅适用于我们的PyTorch实现。
+
+
+[[autodoc]] StoppingCriteria
+ - __call__
+
+[[autodoc]] StoppingCriteriaList
+ - __call__
+
+[[autodoc]] MaxLengthCriteria
+ - __call__
+
+[[autodoc]] MaxTimeCriteria
+ - __call__
+
+## Constraints
+
+可以使用[`Constraint`]来强制生成结果包含输出中的特定tokens或序列。请注意,这仅适用于我们的PyTorch实现。
+
+[[autodoc]] Constraint
+
+[[autodoc]] PhrasalConstraint
+
+[[autodoc]] DisjunctiveConstraint
+
+[[autodoc]] ConstraintListState
+
+## BeamSearch
+
+[[autodoc]] BeamScorer
+ - process
+ - finalize
+
+[[autodoc]] BeamSearchScorer
+ - process
+ - finalize
+
+[[autodoc]] ConstrainedBeamSearchScorer
+ - process
+ - finalize
+
+## Streamers
+
+[[autodoc]] TextStreamer
+
+[[autodoc]] TextIteratorStreamer
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/image_processing_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/image_processing_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..b3c784fa345237a97c6cb60bcdb5939248b57043
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/image_processing_utils.md
@@ -0,0 +1,48 @@
+
+
+# Image Processors的工具
+
+此页面列出了image processors使用的所有实用函数功能,主要是用于处理图像的功能变换。
+
+其中大多数仅在您研究库中image processors的代码时有用。
+
+
+## 图像转换
+
+[[autodoc]] image_transforms.center_crop
+
+[[autodoc]] image_transforms.center_to_corners_format
+
+[[autodoc]] image_transforms.corners_to_center_format
+
+[[autodoc]] image_transforms.id_to_rgb
+
+[[autodoc]] image_transforms.normalize
+
+[[autodoc]] image_transforms.pad
+
+[[autodoc]] image_transforms.rgb_to_id
+
+[[autodoc]] image_transforms.rescale
+
+[[autodoc]] image_transforms.resize
+
+[[autodoc]] image_transforms.to_pil_image
+
+## ImageProcessingMixin
+
+[[autodoc]] image_processing_utils.ImageProcessingMixin
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/modeling_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/modeling_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..93341b323e836b944b30ab6fa009c58dd8a26b64
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/modeling_utils.md
@@ -0,0 +1,83 @@
+
+
+# 自定义层和工具
+
+此页面列出了库使用的所有自定义层,以及它为模型提供的实用函数。
+
+其中大多数只有在您研究库中模型的代码时才有用。
+
+
+## Pytorch自定义模块
+
+[[autodoc]] pytorch_utils.Conv1D
+
+[[autodoc]] modeling_utils.PoolerStartLogits
+ - forward
+
+[[autodoc]] modeling_utils.PoolerEndLogits
+ - forward
+
+[[autodoc]] modeling_utils.PoolerAnswerClass
+ - forward
+
+[[autodoc]] modeling_utils.SquadHeadOutput
+
+[[autodoc]] modeling_utils.SQuADHead
+ - forward
+
+[[autodoc]] modeling_utils.SequenceSummary
+ - forward
+
+## PyTorch帮助函数
+
+[[autodoc]] pytorch_utils.apply_chunking_to_forward
+
+[[autodoc]] pytorch_utils.find_pruneable_heads_and_indices
+
+[[autodoc]] pytorch_utils.prune_layer
+
+[[autodoc]] pytorch_utils.prune_conv1d_layer
+
+[[autodoc]] pytorch_utils.prune_linear_layer
+
+## TensorFlow自定义层
+
+[[autodoc]] modeling_tf_utils.TFConv1D
+
+[[autodoc]] modeling_tf_utils.TFSequenceSummary
+
+## TensorFlow loss 函数
+
+[[autodoc]] modeling_tf_utils.TFCausalLanguageModelingLoss
+
+[[autodoc]] modeling_tf_utils.TFMaskedLanguageModelingLoss
+
+[[autodoc]] modeling_tf_utils.TFMultipleChoiceLoss
+
+[[autodoc]] modeling_tf_utils.TFQuestionAnsweringLoss
+
+[[autodoc]] modeling_tf_utils.TFSequenceClassificationLoss
+
+[[autodoc]] modeling_tf_utils.TFTokenClassificationLoss
+
+## TensorFlow帮助函数
+
+[[autodoc]] modeling_tf_utils.get_initializer
+
+[[autodoc]] modeling_tf_utils.keras_serializable
+
+[[autodoc]] modeling_tf_utils.shape_list
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/pipelines_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/pipelines_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..30fdb8cd1d400626ed56558dd5764ed55f0989e5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/pipelines_utils.md
@@ -0,0 +1,45 @@
+
+
+# pipelines的工具
+
+
+此页面列出了库为pipelines提供的所有实用程序功能。
+
+其中大多数只有在您研究库中模型的代码时才有用。
+
+
+## 参数处理
+
+[[autodoc]] pipelines.ArgumentHandler
+
+[[autodoc]] pipelines.ZeroShotClassificationArgumentHandler
+
+[[autodoc]] pipelines.QuestionAnsweringArgumentHandler
+
+## 数据格式
+
+[[autodoc]] pipelines.PipelineDataFormat
+
+[[autodoc]] pipelines.CsvPipelineDataFormat
+
+[[autodoc]] pipelines.JsonPipelineDataFormat
+
+[[autodoc]] pipelines.PipedPipelineDataFormat
+
+## 实用函数
+
+[[autodoc]] pipelines.PipelineException
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/time_series_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/time_series_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..4b9093fbf478c5c12f98535ca229c35cd58d2305
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/time_series_utils.md
@@ -0,0 +1,31 @@
+
+
+# 时间序列工具
+
+
+此页面列出了可用于时间序列类模型的所有实用函数和类。
+
+其中大多数仅在您研究时间序列模型的代码,或希望添加到分布输出类集合时有用。
+
+
+## 输出分布
+
+[[autodoc]] time_series_utils.NormalOutput
+
+[[autodoc]] time_series_utils.StudentTOutput
+
+[[autodoc]] time_series_utils.NegativeBinomialOutput
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/tokenization_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/tokenization_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..9f216131c122efe7675f8861d1f135b971e75ef3
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/tokenization_utils.md
@@ -0,0 +1,43 @@
+
+
+# Tokenizers的工具
+
+并保留格式:此页面列出了tokenizers使用的所有实用函数,主要是类
+[`~tokenization_utils_base.PreTrained TokenizerBase`] 实现了常用方法之间的
+[`PreTrained Tokenizer`] 和 [`PreTrained TokenizerFast`] 以及混合类
+[`~tokenization_utils_base.SpecialTokens Mixin`]。
+
+其中大多数只有在您研究库中tokenizers的代码时才有用。
+
+
+## PreTrainedTokenizerBase
+
+[[autodoc]] tokenization_utils_base.PreTrainedTokenizerBase
+ - __call__
+ - all
+
+## SpecialTokensMixin
+
+[[autodoc]] tokenization_utils_base.SpecialTokensMixin
+
+## Enums和namedtuples(命名元组)
+
+[[autodoc]] tokenization_utils_base.TruncationStrategy
+
+[[autodoc]] tokenization_utils_base.CharSpan
+
+[[autodoc]] tokenization_utils_base.TokenSpan
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/trainer_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/trainer_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..fc28ba623c9d60576cb118135187fb6e3447f5d5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/internal/trainer_utils.md
@@ -0,0 +1,50 @@
+
+
+# Trainer的工具
+
+此页面列出了 [`Trainer`] 使用的所有实用函数。
+
+其中大多数仅在您研究库中Trainer的代码时有用。
+
+
+## 工具
+
+[[autodoc]] EvalPrediction
+
+[[autodoc]] IntervalStrategy
+
+[[autodoc]] enable_full_determinism
+
+[[autodoc]] set_seed
+
+[[autodoc]] torch_distributed_zero_first
+
+## Callbacks内部机制
+
+[[autodoc]] trainer_callback.CallbackHandler
+
+## 分布式评估
+
+[[autodoc]] trainer_pt_utils.DistributedTensorGatherer
+
+## Trainer参数解析
+
+[[autodoc]] HfArgumentParser
+
+## Debug工具
+
+[[autodoc]] debug_utils.DebugUnderflowOverflow
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/llm_tutorial.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/llm_tutorial.md
new file mode 100644
index 0000000000000000000000000000000000000000..35e62aac3dc0f3f822badb20276d9069e7802797
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/llm_tutorial.md
@@ -0,0 +1,269 @@
+
+
+
+## 使用LLMs进行生成
+
+[[open-in-colab]]
+
+LLMs,即大语言模型,是文本生成背后的关键组成部分。简单来说,它们包含经过大规模预训练的transformer模型,用于根据给定的输入文本预测下一个词(或更准确地说,下一个`token`)。由于它们一次只预测一个`token`,因此除了调用模型之外,您需要执行更复杂的操作来生成新的句子——您需要进行自回归生成。
+
+自回归生成是在给定一些初始输入,通过迭代调用模型及其自身的生成输出来生成文本的推理过程。在🤗 Transformers中,这由[`~generation.GenerationMixin.generate`]方法处理,所有具有生成能力的模型都可以使用该方法。
+
+本教程将向您展示如何:
+
+* 使用LLM生成文本
+* 避免常见的陷阱
+* 帮助您充分利用LLM下一步指导
+
+在开始之前,请确保已安装所有必要的库:
+
+
+```bash
+pip install transformers bitsandbytes>=0.39.0 -q
+```
+
+
+## 生成文本
+
+一个用于[因果语言建模](tasks/language_modeling)训练的语言模型,将文本`tokens`序列作为输入,并返回下一个`token`的概率分布。
+
+
+
+
+ "LLM的前向传递"
+
+
+使用LLM进行自回归生成的一个关键方面是如何从这个概率分布中选择下一个`token`。这个步骤可以随意进行,只要最终得到下一个迭代的`token`。这意味着可以简单的从概率分布中选择最可能的`token`,也可以复杂的在对结果分布进行采样之前应用多种变换,这取决于你的需求。
+
+
+
+ "自回归生成迭代地从概率分布中选择下一个token以生成文本"
+
+
+上述过程是迭代重复的,直到达到某个停止条件。理想情况下,停止条件由模型决定,该模型应学会在何时输出一个结束序列(`EOS`)标记。如果不是这种情况,生成将在达到某个预定义的最大长度时停止。
+
+正确设置`token`选择步骤和停止条件对于让你的模型按照预期的方式执行任务至关重要。这就是为什么我们为每个模型都有一个[~generation.GenerationConfig]文件,它包含一个效果不错的默认生成参数配置,并与您模型一起加载。
+
+让我们谈谈代码!
+
+
+
+如果您对基本的LLM使用感兴趣,我们高级的[`Pipeline`](pipeline_tutorial)接口是一个很好的起点。然而,LLMs通常需要像`quantization`和`token选择步骤的精细控制`等高级功能,这最好通过[`~generation.GenerationMixin.generate`]来完成。使用LLM进行自回归生成也是资源密集型的操作,应该在GPU上执行以获得足够的吞吐量。
+
+
+
+首先,您需要加载模型。
+
+```py
+>>> from transformers import AutoModelForCausalLM
+
+>>> model = AutoModelForCausalLM.from_pretrained(
+... "mistralai/Mistral-7B-v0.1", device_map="auto", load_in_4bit=True
+... )
+```
+
+您将会注意到在`from_pretrained`调用中的两个标志:
+
+- `device_map`确保模型被移动到您的GPU(s)上
+- `load_in_4bit`应用[4位动态量化](main_classes/quantization)来极大地减少资源需求
+
+还有其他方式来初始化一个模型,但这是一个开始使用LLM很好的起点。
+
+接下来,你需要使用一个[tokenizer](tokenizer_summary)来预处理你的文本输入。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-v0.1", padding_side="left")
+>>> model_inputs = tokenizer(["A list of colors: red, blue"], return_tensors="pt").to("cuda")
+```
+
+`model_inputs`变量保存着分词后的文本输入以及注意力掩码。尽管[`~generation.GenerationMixin.generate`]在未传递注意力掩码时会尽其所能推断出注意力掩码,但建议尽可能传递它以获得最佳结果。
+
+在对输入进行分词后,可以调用[`~generation.GenerationMixin.generate`]方法来返回生成的`tokens`。生成的`tokens`应该在打印之前转换为文本。
+
+```py
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'A list of colors: red, blue, green, yellow, orange, purple, pink,'
+```
+
+最后,您不需要一次处理一个序列!您可以批量输入,这将在小延迟和低内存成本下显著提高吞吐量。您只需要确保正确地填充您的输入(详见下文)。
+
+```py
+>>> tokenizer.pad_token = tokenizer.eos_token # Most LLMs don't have a pad token by default
+>>> model_inputs = tokenizer(
+... ["A list of colors: red, blue", "Portugal is"], return_tensors="pt", padding=True
+... ).to("cuda")
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+['A list of colors: red, blue, green, yellow, orange, purple, pink,',
+'Portugal is a country in southwestern Europe, on the Iber']
+```
+
+就是这样!在几行代码中,您就可以利用LLM的强大功能。
+
+
+## 常见陷阱
+
+有许多[生成策略](generation_strategies),有时默认值可能不适合您的用例。如果您的输出与您期望的结果不匹配,我们已经创建了一个最常见的陷阱列表以及如何避免它们。
+
+```py
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-v0.1")
+>>> tokenizer.pad_token = tokenizer.eos_token # Most LLMs don't have a pad token by default
+>>> model = AutoModelForCausalLM.from_pretrained(
+... "mistralai/Mistral-7B-v0.1", device_map="auto", load_in_4bit=True
+... )
+```
+
+### 生成的输出太短/太长
+
+如果在[`~generation.GenerationConfig`]文件中没有指定,`generate`默认返回20个tokens。我们强烈建议在您的`generate`调用中手动设置`max_new_tokens`以控制它可以返回的最大新tokens数量。请注意,LLMs(更准确地说,仅[解码器模型](https://huggingface.co/learn/nlp-course/chapter1/6?fw=pt))也将输入提示作为输出的一部分返回。
+
+```py
+>>> model_inputs = tokenizer(["A sequence of numbers: 1, 2"], return_tensors="pt").to("cuda")
+
+>>> # By default, the output will contain up to 20 tokens
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'A sequence of numbers: 1, 2, 3, 4, 5'
+
+>>> # Setting `max_new_tokens` allows you to control the maximum length
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=50)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'A sequence of numbers: 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16,'
+```
+
+### 错误的生成模式
+
+默认情况下,除非在[`~generation.GenerationConfig`]文件中指定,否则`generate`会在每个迭代中选择最可能的token(贪婪解码)。对于您的任务,这可能是不理想的;像聊天机器人或写作文章这样的创造性任务受益于采样。另一方面,像音频转录或翻译这样的基于输入的任务受益于贪婪解码。通过将`do_sample=True`启用采样,您可以在这篇[博客文章](https://huggingface.co/blog/how-to-generate)中了解更多关于这个话题的信息。
+
+```py
+>>> # Set seed or reproducibility -- you don't need this unless you want full reproducibility
+>>> from transformers import set_seed
+>>> set_seed(42)
+
+>>> model_inputs = tokenizer(["I am a cat."], return_tensors="pt").to("cuda")
+
+>>> # LLM + greedy decoding = repetitive, boring output
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'I am a cat. I am a cat. I am a cat. I am a cat'
+
+>>> # With sampling, the output becomes more creative!
+>>> generated_ids = model.generate(**model_inputs, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'I am a cat. Specifically, I am an indoor-only cat. I'
+```
+
+### 错误的填充位置
+
+LLMs是[仅解码器](https://huggingface.co/learn/nlp-course/chapter1/6?fw=pt)架构,意味着它们会持续迭代您的输入提示。如果您的输入长度不相同,则需要对它们进行填充。由于LLMs没有接受过从`pad tokens`继续训练,因此您的输入需要左填充。确保在生成时不要忘记传递注意力掩码!
+
+```py
+>>> # The tokenizer initialized above has right-padding active by default: the 1st sequence,
+>>> # which is shorter, has padding on the right side. Generation fails to capture the logic.
+>>> model_inputs = tokenizer(
+... ["1, 2, 3", "A, B, C, D, E"], padding=True, return_tensors="pt"
+... ).to("cuda")
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'1, 2, 33333333333'
+
+>>> # With left-padding, it works as expected!
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-v0.1", padding_side="left")
+>>> tokenizer.pad_token = tokenizer.eos_token # Most LLMs don't have a pad token by default
+>>> model_inputs = tokenizer(
+... ["1, 2, 3", "A, B, C, D, E"], padding=True, return_tensors="pt"
+... ).to("cuda")
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'1, 2, 3, 4, 5, 6,'
+```
+
+### 错误的提示
+
+一些模型和任务期望某种输入提示格式才能正常工作。当未应用此格式时,您将获得悄然的性能下降:模型能工作,但不如预期提示那样好。有关提示的更多信息,包括哪些模型和任务需要小心,可在[指南](tasks/prompting)中找到。让我们看一个使用[聊天模板](chat_templating)的聊天LLM示例:
+
+```python
+>>> tokenizer = AutoTokenizer.from_pretrained("HuggingFaceH4/zephyr-7b-alpha")
+>>> model = AutoModelForCausalLM.from_pretrained(
+... "HuggingFaceH4/zephyr-7b-alpha", device_map="auto", load_in_4bit=True
+... )
+>>> set_seed(0)
+>>> prompt = """How many helicopters can a human eat in one sitting? Reply as a thug."""
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to("cuda")
+>>> input_length = model_inputs.input_ids.shape[1]
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=20)
+>>> print(tokenizer.batch_decode(generated_ids[:, input_length:], skip_special_tokens=True)[0])
+"I'm not a thug, but i can tell you that a human cannot eat"
+>>> # Oh no, it did not follow our instruction to reply as a thug! Let's see what happens when we write
+>>> # a better prompt and use the right template for this model (through `tokenizer.apply_chat_template`)
+
+>>> set_seed(0)
+>>> messages = [
+... {
+... "role": "system",
+... "content": "You are a friendly chatbot who always responds in the style of a thug",
+... },
+... {"role": "user", "content": "How many helicopters can a human eat in one sitting?"},
+... ]
+>>> model_inputs = tokenizer.apply_chat_template(messages, add_generation_prompt=True, return_tensors="pt").to("cuda")
+>>> input_length = model_inputs.shape[1]
+>>> generated_ids = model.generate(model_inputs, do_sample=True, max_new_tokens=20)
+>>> print(tokenizer.batch_decode(generated_ids[:, input_length:], skip_special_tokens=True)[0])
+'None, you thug. How bout you try to focus on more useful questions?'
+>>> # As we can see, it followed a proper thug style 😎
+```
+
+## 更多资源
+
+虽然自回归生成过程相对简单,但要充分利用LLM可能是一个具有挑战性的任务,因为很多组件复杂且密切关联。以下是帮助您深入了解LLM使用和理解的下一步:
+
+### 高级生成用法
+
+1. [指南](generation_strategies),介绍如何控制不同的生成方法、如何设置生成配置文件以及如何进行输出流式传输;
+2. [指南](chat_templating),介绍聊天LLMs的提示模板;
+3. [指南](tasks/prompting),介绍如何充分利用提示设计;
+4. API参考文档,包括[`~generation.GenerationConfig`]、[`~generation.GenerationMixin.generate`]和[与生成相关的类](internal/generation_utils)。
+
+### LLM排行榜
+
+1. [Open LLM Leaderboard](https://huggingface.co/spaces/HuggingFaceH4/open_llm_leaderboard), 侧重于开源模型的质量;
+2. [Open LLM-Perf Leaderboard](https://huggingface.co/spaces/optimum/llm-perf-leaderboard), 侧重于LLM的吞吐量.
+
+### 延迟、吞吐量和内存利用率
+
+1. [指南](llm_tutorial_optimization),如何优化LLMs以提高速度和内存利用;
+2. [指南](main_classes/quantization), 关于`quantization`,如bitsandbytes和autogptq的指南,教您如何大幅降低内存需求。
+
+### 相关库
+
+1. [`text-generation-inference`](https://github.com/huggingface/text-generation-inference), 一个面向生产的LLM服务器;
+2. [`optimum`](https://github.com/huggingface/optimum), 一个🤗 Transformers的扩展,优化特定硬件设备的性能
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/agent.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/agent.md
new file mode 100644
index 0000000000000000000000000000000000000000..b35a382feb9797ffe4870bde9465a021952530ff
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/agent.md
@@ -0,0 +1,26 @@
+
+
+# Agents和工具
+
+
+
+The Agents framework has significantly changed in version v4.41.0.
+This document has been removed as it was referencing an older API.
+
+We eagerly welcome new contributions for the updated API.
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/callback.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/callback.md
new file mode 100644
index 0000000000000000000000000000000000000000..3642207d75b95151b21e58d9131341aff7f59020
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/callback.md
@@ -0,0 +1,125 @@
+
+
+# Callbacks
+
+
+Callbacks可以用来自定义PyTorch [Trainer]中训练循环行为的对象(此功能尚未在TensorFlow中实现),该对象可以检查训练循环状态(用于进度报告、在TensorBoard或其他ML平台上记录日志等),并做出决策(例如提前停止)。
+
+Callbacks是“只读”的代码片段,除了它们返回的[TrainerControl]对象外,它们不能更改训练循环中的任何内容。对于需要更改训练循环的自定义,您应该继承[Trainer]并重载您需要的方法(有关示例,请参见[trainer](trainer))。
+
+默认情况下,`TrainingArguments.report_to` 设置为"all",然后[Trainer]将使用以下callbacks。
+
+
+- [`DefaultFlowCallback`],它处理默认的日志记录、保存和评估行为
+- [`PrinterCallback`] 或 [`ProgressCallback`],用于显示进度和打印日志(如果通过[`TrainingArguments`]停用tqdm,则使用第一个函数;否则使用第二个)。
+- [`~integrations.TensorBoardCallback`],如果TensorBoard可访问(通过PyTorch版本 >= 1.4 或者 tensorboardX)。
+- [`~integrations.WandbCallback`],如果安装了[wandb](https://www.wandb.com/)。
+- [`~integrations.CometCallback`],如果安装了[comet_ml](https://www.comet.com/site/)。
+- [`~integrations.MLflowCallback`],如果安装了[mlflow](https://www.mlflow.org/)。
+- [`~integrations.NeptuneCallback`],如果安装了[neptune](https://neptune.ai/)。
+- [`~integrations.AzureMLCallback`],如果安装了[azureml-sdk](https://pypi.org/project/azureml-sdk/)。
+- [`~integrations.CodeCarbonCallback`],如果安装了[codecarbon](https://pypi.org/project/codecarbon/)。
+- [`~integrations.ClearMLCallback`],如果安装了[clearml](https://github.com/allegroai/clearml)。
+- [`~integrations.DagsHubCallback`],如果安装了[dagshub](https://dagshub.com/)。
+- [`~integrations.FlyteCallback`],如果安装了[flyte](https://flyte.org/)。
+- [`~integrations.DVCLiveCallback`],如果安装了[dvclive](https://dvc.org/doc/dvclive)。
+
+如果安装了一个软件包,但您不希望使用相关的集成,您可以将 `TrainingArguments.report_to` 更改为仅包含您想要使用的集成的列表(例如 `["azure_ml", "wandb"]`)。
+
+实现callbacks的主要类是[`TrainerCallback`]。它获取用于实例化[`Trainer`]的[`TrainingArguments`],可以通过[`TrainerState`]访问该Trainer的内部状态,并可以通过[`TrainerControl`]对训练循环执行一些操作。
+
+
+## 可用的Callbacks
+
+这里是库里可用[`TrainerCallback`]的列表:
+
+[[autodoc]] integrations.CometCallback
+ - setup
+
+[[autodoc]] DefaultFlowCallback
+
+[[autodoc]] PrinterCallback
+
+[[autodoc]] ProgressCallback
+
+[[autodoc]] EarlyStoppingCallback
+
+[[autodoc]] integrations.TensorBoardCallback
+
+[[autodoc]] integrations.WandbCallback
+ - setup
+
+[[autodoc]] integrations.MLflowCallback
+ - setup
+
+[[autodoc]] integrations.AzureMLCallback
+
+[[autodoc]] integrations.CodeCarbonCallback
+
+[[autodoc]] integrations.NeptuneCallback
+
+[[autodoc]] integrations.ClearMLCallback
+
+[[autodoc]] integrations.DagsHubCallback
+
+[[autodoc]] integrations.FlyteCallback
+
+[[autodoc]] integrations.DVCLiveCallback
+ - setup
+
+## TrainerCallback
+
+[[autodoc]] TrainerCallback
+
+以下是如何使用PyTorch注册自定义callback的示例:
+
+[`Trainer`]:
+
+```python
+class MyCallback(TrainerCallback):
+ "A callback that prints a message at the beginning of training"
+
+ def on_train_begin(self, args, state, control, **kwargs):
+ print("Starting training")
+
+
+trainer = Trainer(
+ model,
+ args,
+ train_dataset=train_dataset,
+ eval_dataset=eval_dataset,
+ callbacks=[MyCallback], # We can either pass the callback class this way or an instance of it (MyCallback())
+)
+```
+
+注册callback的另一种方式是调用 `trainer.add_callback()`,如下所示:
+
+
+```python
+trainer = Trainer(...)
+trainer.add_callback(MyCallback)
+# Alternatively, we can pass an instance of the callback class
+trainer.add_callback(MyCallback())
+```
+
+## TrainerState
+
+[[autodoc]] TrainerState
+
+## TrainerControl
+
+[[autodoc]] TrainerControl
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/configuration.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/configuration.md
new file mode 100644
index 0000000000000000000000000000000000000000..755a3170419bf4c7fc6f5e391436202a44e7f51f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/configuration.md
@@ -0,0 +1,28 @@
+
+
+# Configuration
+
+基类[`PretrainedConfig`]实现了从本地文件或目录加载/保存配置的常见方法,或下载库提供的预训练模型配置(从HuggingFace的AWS S3库中下载)。
+
+每个派生的配置类都实现了特定于模型的属性。所有配置类中共同存在的属性有:`hidden_size`、`num_attention_heads` 和 `num_hidden_layers`。文本模型进一步添加了 `vocab_size`。
+
+
+## PretrainedConfig
+
+[[autodoc]] PretrainedConfig
+ - push_to_hub
+ - all
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/data_collator.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/data_collator.md
new file mode 100644
index 0000000000000000000000000000000000000000..d947b53ea14cb2e17b287a68067f92f9894efb88
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/data_collator.md
@@ -0,0 +1,65 @@
+
+
+# Data Collator
+
+Data collators是一个对象,通过使用数据集元素列表作为输入来形成一个批次。这些元素与 `train_dataset` 或 `eval_dataset` 的元素类型相同。
+
+为了能够构建批次,Data collators可能会应用一些预处理(比如填充)。其中一些(比如[`DataCollatorForLanguageModeling`])还会在形成的批次上应用一些随机数据增强(比如随机掩码)。
+
+在[示例脚本](../examples)或[示例notebooks](../notebooks)中可以找到使用的示例。
+
+
+## Default data collator
+
+[[autodoc]] data.data_collator.default_data_collator
+
+## DefaultDataCollator
+
+[[autodoc]] data.data_collator.DefaultDataCollator
+
+## DataCollatorWithPadding
+
+[[autodoc]] data.data_collator.DataCollatorWithPadding
+
+## DataCollatorForTokenClassification
+
+[[autodoc]] data.data_collator.DataCollatorForTokenClassification
+
+## DataCollatorForSeq2Seq
+
+[[autodoc]] data.data_collator.DataCollatorForSeq2Seq
+
+## DataCollatorForLanguageModeling
+
+[[autodoc]] data.data_collator.DataCollatorForLanguageModeling
+ - numpy_mask_tokens
+ - tf_mask_tokens
+ - torch_mask_tokens
+
+## DataCollatorForWholeWordMask
+
+[[autodoc]] data.data_collator.DataCollatorForWholeWordMask
+ - numpy_mask_tokens
+ - tf_mask_tokens
+ - torch_mask_tokens
+
+## DataCollatorForPermutationLanguageModeling
+
+[[autodoc]] data.data_collator.DataCollatorForPermutationLanguageModeling
+ - numpy_mask_tokens
+ - tf_mask_tokens
+ - torch_mask_tokens
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/deepspeed.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/deepspeed.md
new file mode 100644
index 0000000000000000000000000000000000000000..75a0a13df75e24d21a3249f40a5872dd2db5671c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/deepspeed.md
@@ -0,0 +1,2100 @@
+
+
+# DeepSpeed集成
+
+[DeepSpeed](https://github.com/microsoft/DeepSpeed)实现了[ZeRO论文](https://arxiv.org/abs/1910.02054)中描述的所有内容。目前,它提供对以下功能的全面支持:
+
+1. 优化器状态分区(ZeRO stage 1)
+2. 梯度分区(ZeRO stage 2)
+3. 参数分区(ZeRO stage 3)
+4. 自定义混合精度训练处理
+5. 一系列基于CUDA扩展的快速优化器
+6. ZeRO-Offload 到 CPU 和 NVMe
+
+ZeRO-Offload有其自己的专门论文:[ZeRO-Offload: Democratizing Billion-Scale Model Training](https://arxiv.org/abs/2101.06840)。而NVMe支持在论文[ZeRO-Infinity: Breaking the GPU Memory Wall for Extreme Scale Deep Learning](https://arxiv.org/abs/2104.07857)中进行了描述。
+
+DeepSpeed ZeRO-2主要用于训练,因为它的特性对推理没有用处。
+
+DeepSpeed ZeRO-3也可以用于推理,因为它允许将单个GPU无法加载的大模型加载到多个GPU上。
+
+🤗 Transformers通过以下两种方式集成了[DeepSpeed](https://github.com/microsoft/DeepSpeed):
+
+1. 通过[`Trainer`]集成核心的DeepSpeed功能。这是一种“为您完成一切”式的集成 - 您只需提供自定义配置文件或使用我们的模板配置文件。本文档的大部分内容都集中在这个功能上。
+2. 如果您不使用[`Trainer`]并希望在自己的Trainer中集成DeepSpeed,那么像`from_pretrained`和`from_config`这样的核心功能函数将包括ZeRO stage 3及以上的DeepSpeed的基础部分,如`zero.Init`。要利用此功能,请阅读有关[非Trainer DeepSpeed集成](#nontrainer-deepspeed-integration)的文档。
+
+集成的内容:
+
+训练:
+
+1. DeepSpeed ZeRO训练支持完整的ZeRO stages 1、2和3,以及ZeRO-Infinity(CPU和NVMe offload)。
+
+推理:
+
+1. DeepSpeed ZeRO推理支持ZeRO stage 3和ZeRO-Infinity。它使用与训练相同的ZeRO协议,但不使用优化器和学习率调度器,只有stage 3与推理相关。更多详细信息请参阅:[zero-inference](#zero-inference)。
+
+此外还有DeepSpeed推理 - 这是一种完全不同的技术,它使用张量并行而不是ZeRO(即将推出)。
+
+
+ --deepspeed ds_config.json
+```
+
+或使用由 `deepspeed` 提供的启动器:
+
+
+```bash
+deepspeed --num_gpus=2 your_program.py --deepspeed ds_config.json
+```
+
+
+正如您所见,这两个启动器的参数不同,但对于大多数需求,任何一个都可以满足工作需求。有关如何配置各个节点和 GPU 的完整详细信息,请查看 [此处](https://www.deepspeed.ai/getting-started/#resource-configuration-multi-node)。
+
+当您使用 `deepspeed` 启动器并且希望使用所有可用的 GPU 时,您可以简单地省略 `--num_gpus` 标志。
+
+以下是在 DeepSpeed 中启用使用所有可用 GPU情况下, 运行 `run_translation.py` 的示例:
+
+
+```bash
+deepspeed examples/pytorch/translation/run_translation.py \
+--deepspeed tests/deepspeed/ds_config_zero3.json \
+--model_name_or_path google-t5/t5-small --per_device_train_batch_size 1 \
+--output_dir output_dir --overwrite_output_dir --fp16 \
+--do_train --max_train_samples 500 --num_train_epochs 1 \
+--dataset_name wmt16 --dataset_config "ro-en" \
+--source_lang en --target_lang ro
+```
+
+请注意,在 DeepSpeed 文档中,您可能会看到 `--deepspeed --deepspeed_config ds_config.json` - 即两个与 DeepSpeed 相关的参数,但为简单起见,并且因为已经有很多参数要处理,我们将两者合并为一个单一参数。
+
+有关一些实际使用示例,请参阅 [此帖](https://github.com/huggingface/transformers/issues/8771#issuecomment-759248400)。
+
+
+
+ --deepspeed ds_config.json
+```
+
+您必须 ssh 到每个节点,并在每个节点上运行相同的命令!不用担心,启动器会等待两个节点同步完成。
+
+有关更多信息,请参阅 [torchrun](https://pytorch.org/docs/stable/elastic/run.html)。顺便说一下,这也是替代了几个 PyTorch 版本前的 `torch.distributed.launch` 的启动器。
+
+
+#### deepspeed启动器
+
+要改用 `deepspeed` 启动器,首先需要创建一个 `hostfile` 文件:
+
+```
+hostname1 slots=8
+hostname2 slots=8
+```
+然后,您可以这样启动:
+
+```bash
+deepspeed --num_gpus 8 --num_nodes 2 --hostfile hostfile --master_addr hostname1 --master_port=9901 \
+your_program.py --deepspeed ds_config.json
+```
+
+与 `torch.distributed.run` 启动器不同,`deepspeed` 将自动在两个节点上启动此命令!
+
+更多信息,请参阅[资源配置(多节点)](https://www.deepspeed.ai/getting-started/#resource-configuration-multi-node)。
+
+
+#### 在 SLURM 环境中启动
+
+在 SLURM 环境中,可以采用以下方法。以下是一个 SLURM 脚本 `launch.slurm`,您需要根据您的具体 SLURM 环境进行调整。
+
+```bash
+#SBATCH --job-name=test-nodes # name
+#SBATCH --nodes=2 # nodes
+#SBATCH --ntasks-per-node=1 # crucial - only 1 task per dist per node!
+#SBATCH --cpus-per-task=10 # number of cores per tasks
+#SBATCH --gres=gpu:8 # number of gpus
+#SBATCH --time 20:00:00 # maximum execution time (HH:MM:SS)
+#SBATCH --output=%x-%j.out # output file name
+
+export GPUS_PER_NODE=8
+export MASTER_ADDR=$(scontrol show hostnames $SLURM_JOB_NODELIST | head -n 1)
+export MASTER_PORT=9901
+
+srun --jobid $SLURM_JOBID bash -c 'python -m torch.distributed.run \
+ --nproc_per_node $GPUS_PER_NODE --nnodes $SLURM_NNODES --node_rank $SLURM_PROCID \
+ --master_addr $MASTER_ADDR --master_port $MASTER_PORT \
+your_program.py --deepspeed ds_config.json'
+```
+
+剩下的就是运行它:
+
+```bash
+sbatch launch.slurm
+```
+
+`srun` 将负责在所有节点上同时启动程序。
+
+
+#### 使用非共享文件系统
+
+默认情况下,DeepSpeed 假定多节点环境使用共享存储。如果不是这种情况,每个节点只能看到本地文件系统,你需要调整配置文件,包含一个 [`checkpoint` 部分](https://www.deepspeed.ai/docs/config-json/#checkpoint-options)并设置如下选项:
+
+```json
+{
+ "checkpoint": {
+ "use_node_local_storage": true
+ }
+}
+```
+
+或者,你还可以使用 [`Trainer`] 的 `--save_on_each_node` 参数,上述配置将自动添加。
+
+
+
+
+这一部分是必读的。
+
+
+
+一些配置值对于 [`Trainer`] 和 DeepSpeed 正常运行都是必需的,因此,为了防止定义冲突及导致的难以检测的错误,我们选择通过 [`Trainer`] 命令行参数配置这些值。
+
+此外,一些配置值是基于模型的配置自动派生的,因此,与其记住手动调整多个值,最好让 [`Trainer`] 为您做大部分配置。
+
+因此,在本指南的其余部分,您将找到一个特殊的配置值:`auto`,当设置时将自动将参数替换为正确或最有效的值。请随意选择忽略此建议或显式设置该值,在这种情况下,请务必确保 [`Trainer`] 参数和 DeepSpeed 配置保持一致。例如,您是否使用相同的学习率、批量大小或梯度累积设置?如果这些不匹配,训练可能以非常难以检测的方式失败。请重视该警告。
+
+还有一些参数是仅适用于 DeepSpeed 的,并且这些参数必须手动设置以适应您的需求。
+
+在您自己的程序中,如果您想要作为主动修改 DeepSpeed 配置并以此配置 [`TrainingArguments`],您还可以使用以下方法。步骤如下:
+
+1. 创建或加载要用作主配置的 DeepSpeed 配置
+2. 根据这些参数值创建 [`TrainingArguments`] 对象
+
+请注意,一些值,比如 `scheduler.params.total_num_steps`,是在 [`Trainer`] 的 `train` 过程中计算的,但当然您也可以自己计算这些值。
+
+
+
+
+在`deepspeed==0.6.0`版本中,bf16支持是新的实验性功能。
+
+如果您启用了bf16来进行[梯度累积](#gradient-accumulation),您需要意识到它会以bf16累积梯度,这可能不是您想要的,因为这种格式的低精度可能会导致lossy accumulation。
+
+修复这个问题的工作正在努力进行,同时提供了使用更高精度的`dtype`(fp16或fp32)的选项。
+
+
+
+
+### NCCL集合
+
+在训练过程中,有两种数据类型:`dtype`和用于通信收集操作的`dtype`,如各种归约和收集/分散操作。
+
+所有的gather/scatter操作都是在数据相同的`dtype`中执行的,所以如果您正在使用bf16的训练模式,那么它将在bf16中进行gather操作 - gather操作是非损失性的。
+
+各种reduce操作可能会是非常损失性的,例如当梯度在多个gpu上平均时,如果通信是在fp16或bf16中进行的,那么结果可能是有损失性的 - 因为当在一个低精度中添加多个数字时,结果可能不是精确的。更糟糕的是,bf16比fp16具有更低的精度。通常,当平均梯度时,损失最小,这些梯度通常非常小。因此,对于半精度训练,默认情况下,fp16被用作reduction操作的默认值。但是,您可以完全控制这个功能,如果你选择的话,您可以添加一个小的开销,并确保reductions将使用fp32作为累积数据类型,只有当结果准备好时,它才会降级到您在训练中使用的半精度`dtype`。
+
+要覆盖默认设置,您只需添加一个新的配置条目:
+
+```json
+{
+ "communication_data_type": "fp32"
+}
+```
+
+根据这个信息,有效的值包括"fp16"、"bfp16"和"fp32"。
+
+注意:在stage zero 3中,bf16通信数据类型存在一个bug,该问题已在`deepspeed==0.8.1`版本中得到修复。
+
+
+### apex
+
+配置apex AMP-like模式:
+
+```json
+"amp": {
+ "enabled": "auto",
+ "opt_level": "auto"
+}
+```
+
+并且,[`Trainer`]将根据`args.fp16_backend`和`args.fp16_opt_level`的值自动配置它。
+
+当传递`--fp16 --fp16_backend apex --fp16_opt_level 01`命令行参数时,此模式将被启用。
+
+您还可以显式配置此模式:
+
+```json
+{
+ "amp": {
+ "enabled": true,
+ "opt_level": "O1"
+ }
+}
+```
+
+但是,您需要自己同步[`Trainer`]命令行参数和DeepSpeed配置。
+
+这里是[文档](https://www.deepspeed.ai/docs/config-json/#automatic-mixed-precision-amp-training-options)
+
+
+
+
+注意,一旦运行了`load_state_dict_from_zero_checkpoint`,该模型将不再可以在相同的应用程序的DeepSpeed上下文中使用。也就是说,您需要重新初始化deepspeed引擎,因为`model.load_state_dict(state_dict)`会从其中移除所有的DeepSpeed相关点。所以您只能训练结束时这样做。
+
+
+
+当然,您不必使用类:*~transformers.Trainer*,您可以根据你的需求调整上面的示例。
+
+如果您出于某种原因想要更多的优化,您也可以提取权重的fp32 `state_dict`并按照以下示例进行操作:
+
+```python
+from deepspeed.utils.zero_to_fp32 import get_fp32_state_dict_from_zero_checkpoint
+
+state_dict = get_fp32_state_dict_from_zero_checkpoint(checkpoint_dir) # already on cpu
+model = model.cpu()
+model.load_state_dict(state_dict)
+```
+
+**离线FP32权重恢复:**
+
+DeepSpeed会创建一个特殊的转换脚本`zero_to_fp32.py`,并将其放置在checkpoint文件夹的顶层。使用此脚本,您可以在任何时候提取权重。该脚本是独立的,您不再需要配置文件或`Trainer`来执行提取操作。
+
+假设您的checkpoint文件夹如下所示:
+
+```bash
+$ ls -l output_dir/checkpoint-1/
+-rw-rw-r-- 1 stas stas 1.4K Mar 27 20:42 config.json
+drwxrwxr-x 2 stas stas 4.0K Mar 25 19:52 global_step1/
+-rw-rw-r-- 1 stas stas 12 Mar 27 13:16 latest
+-rw-rw-r-- 1 stas stas 827K Mar 27 20:42 optimizer.pt
+-rw-rw-r-- 1 stas stas 231M Mar 27 20:42 pytorch_model.bin
+-rw-rw-r-- 1 stas stas 623 Mar 27 20:42 scheduler.pt
+-rw-rw-r-- 1 stas stas 1.8K Mar 27 20:42 special_tokens_map.json
+-rw-rw-r-- 1 stas stas 774K Mar 27 20:42 spiece.model
+-rw-rw-r-- 1 stas stas 1.9K Mar 27 20:42 tokenizer_config.json
+-rw-rw-r-- 1 stas stas 339 Mar 27 20:42 trainer_state.json
+-rw-rw-r-- 1 stas stas 2.3K Mar 27 20:42 training_args.bin
+-rwxrw-r-- 1 stas stas 5.5K Mar 27 13:16 zero_to_fp32.py*
+```
+
+在这个例子中,只有一个DeepSpeed检查点子文件夹*global_step1*。因此,要重构fp32权重,只需运行:
+
+```bash
+python zero_to_fp32.py . pytorch_model.bin
+```
+
+这就是它。`pytorch_model.bin`现在将包含从多个GPUs合并的完整的fp32模型权重。
+
+该脚本将自动能够处理ZeRO-2或ZeRO-3 checkpoint。
+
+`python zero_to_fp32.py -h`将为您提供使用细节。
+
+该脚本将通过文件`latest`的内容自动发现deepspeed子文件夹,在当前示例中,它将包含`global_step1`。
+
+注意:目前该脚本需要2倍于最终fp32模型权重的通用内存。
+
+
+### ZeRO-3 和 Infinity Nuances
+
+ZeRO-3与ZeRO-2有很大的不同,主要是因为它的参数分片功能。
+
+ZeRO-Infinity进一步扩展了ZeRO-3,以支持NVMe内存和其他速度和可扩展性改进。
+
+尽管所有努力都是为了在不需要对模型进行任何特殊更改的情况下就能正常运行,但在某些情况下,您可能需要以下信息。
+
+
+#### 构建大模型
+
+DeepSpeed/ZeRO-3可以处理参数量达到数万亿的模型,这些模型可能无法适应现有的内存。在这种情况下,如果您还是希望初始化更快地发生,可以使用*deepspeed.zero.Init()*上下文管理器(也是一个函数装饰器)来初始化模型,如下所示:
+
+```python
+from transformers import T5ForConditionalGeneration, T5Config
+import deepspeed
+
+with deepspeed.zero.Init():
+ config = T5Config.from_pretrained("google-t5/t5-small")
+ model = T5ForConditionalGeneration(config)
+```
+
+如您所见,这会为您随机初始化一个模型。
+
+如果您想使用预训练模型,`model_class.from_pretrained`将在`is_deepspeed_zero3_enabled()`返回`True`的情况下激活此功能,目前这是通过传递的DeepSpeed配置文件中的ZeRO-3配置部分设置的。因此,在调用`from_pretrained`之前,您必须创建**TrainingArguments**对象。以下是可能的顺序示例:
+
+```python
+from transformers import AutoModel, Trainer, TrainingArguments
+
+training_args = TrainingArguments(..., deepspeed=ds_config)
+model = AutoModel.from_pretrained("google-t5/t5-small")
+trainer = Trainer(model=model, args=training_args, ...)
+```
+
+如果您使用的是官方示例脚本,并且命令行参数中包含`--deepspeed ds_config.json`且启用了ZeRO-3配置,那么一切都已经为您准备好了,因为这是示例脚本的编写方式。
+
+注意:如果模型的fp16权重无法适应单个GPU的内存,则必须使用此功能。
+
+有关此方法和其他相关功能的完整详细信息,请参阅[构建大模型](https://deepspeed.readthedocs.io/en/latest/zero3.html#constructing-massive-models)。
+
+此外,在加载fp16预训练模型时,您希望`from_pretrained`使用`torch_dtype=torch.float16`。详情请参见[from_pretrained-torch-dtype](#from_pretrained-torch-dtype)。
+
+
+#### 参数收集
+
+在多个GPU上使用ZeRO-3时,没有一个GPU拥有所有参数,除非它是当前执行层的参数。因此,如果您需要一次访问所有层的所有参数,有一个特定的方法可以实现。
+您可能不需要它,但如果您需要,请参考[参数收集](https://deepspeed.readthedocs.io/en/latest/zero3.html#manual-parameter-coordination)。
+
+然而,我们在多个地方确实使用了它,其中一个例子是在`from_pretrained`中加载预训练模型权重。我们一次加载一层,然后立即将其分区到所有参与的GPU上,因为对于非常大的模型,无法在一个GPU上一次性加载并将其分布到多个GPU上,因为内存限制。
+
+此外,在ZeRO-3下,如果您编写自己的代码并遇到看起来像这样的模型参数权重:
+
+```python
+tensor([1.0], device="cuda:0", dtype=torch.float16, requires_grad=True)
+```
+
+强调`tensor([1.])`,或者如果您遇到一个错误,它说参数的大小是`1`,而不是某个更大的多维形状,这意味着参数被划分了,你看到的是一个ZeRO-3占位符。
+
+
+
+ --do_eval --deepspeed ds_config.json
+```
+
+唯一的重要事情是您需要使用ZeRO-3配置,因为ZeRO-2对于推理没有任何优势,因为只有ZeRO-3才对参数进行分片,而ZeRO-1则对梯度和优化器状态进行分片。
+
+以下是在DeepSpeed下运行`run_translation.py`启用所有可用GPU的示例:
+
+```bash
+deepspeed examples/pytorch/translation/run_translation.py \
+--deepspeed tests/deepspeed/ds_config_zero3.json \
+--model_name_or_path google-t5/t5-small --output_dir output_dir \
+--do_eval --max_eval_samples 50 --warmup_steps 50 \
+--max_source_length 128 --val_max_target_length 128 \
+--overwrite_output_dir --per_device_eval_batch_size 4 \
+--predict_with_generate --dataset_config "ro-en" --fp16 \
+--source_lang en --target_lang ro --dataset_name wmt16 \
+--source_prefix "translate English to Romanian: "
+```
+
+由于在推理阶段,优化器状态和梯度不需要额外的大量内存,您应该能够将更大的批次和/或序列长度放到相同的硬件上。
+
+此外,DeepSpeed目前正在开发一个名为Deepspeed-Inference的相关产品,它与ZeRO技术无关,而是使用张量并行来扩展无法适应单个GPU的模型。这是一个正在进行的工作,一旦该产品完成,我们将提供集成。
+
+
+### 内存要求
+
+由于 DeepSpeed ZeRO 可以将内存卸载到 CPU(和 NVMe),该框架提供了一些工具,允许根据使用的 GPU 数量告知将需要多少 CPU 和 GPU 内存。
+
+让我们估计在单个GPU上微调"bigscience/T0_3B"所需的内存:
+
+```bash
+$ python -c 'from transformers import AutoModel; \
+from deepspeed.runtime.zero.stage3 import estimate_zero3_model_states_mem_needs_all_live; \
+model = AutoModel.from_pretrained("bigscience/T0_3B"); \
+estimate_zero3_model_states_mem_needs_all_live(model, num_gpus_per_node=1, num_nodes=1)'
+[...]
+Estimated memory needed for params, optim states and gradients for a:
+HW: Setup with 1 node, 1 GPU per node.
+SW: Model with 2783M total params, 65M largest layer params.
+ per CPU | per GPU | Options
+ 70.00GB | 0.25GB | offload_param=cpu , offload_optimizer=cpu , zero_init=1
+ 70.00GB | 0.25GB | offload_param=cpu , offload_optimizer=cpu , zero_init=0
+ 62.23GB | 5.43GB | offload_param=none, offload_optimizer=cpu , zero_init=1
+ 62.23GB | 5.43GB | offload_param=none, offload_optimizer=cpu , zero_init=0
+ 0.37GB | 46.91GB | offload_param=none, offload_optimizer=none, zero_init=1
+ 15.56GB | 46.91GB | offload_param=none, offload_optimizer=none, zero_init=0
+```
+
+因此,您可以将模型拟合在单个80GB的GPU上,不进行CPU offload,或者使用微小的8GB GPU,但需要约60GB的CPU内存。(请注意,这仅是参数、优化器状态和梯度所需的内存 - 您还需要为CUDA内核、激活值和临时变量分配更多的内存。)
+
+然后,这是成本与速度的权衡。购买/租用较小的 GPU(或较少的 GPU,因为您可以使用多个 GPU 进行 Deepspeed ZeRO)。但这样会更慢,因此即使您不关心完成某项任务的速度,减速也直接影响 GPU 使用的持续时间,从而导致更大的成本。因此,请进行实验并比较哪种方法效果最好。
+
+如果您有足够的GPU内存,请确保禁用CPU/NVMe卸载,因为这会使所有操作更快。
+
+例如,让我们重复相同的操作,使用2个GPU:
+
+```bash
+$ python -c 'from transformers import AutoModel; \
+from deepspeed.runtime.zero.stage3 import estimate_zero3_model_states_mem_needs_all_live; \
+model = AutoModel.from_pretrained("bigscience/T0_3B"); \
+estimate_zero3_model_states_mem_needs_all_live(model, num_gpus_per_node=2, num_nodes=1)'
+[...]
+Estimated memory needed for params, optim states and gradients for a:
+HW: Setup with 1 node, 2 GPUs per node.
+SW: Model with 2783M total params, 65M largest layer params.
+ per CPU | per GPU | Options
+ 70.00GB | 0.25GB | offload_param=cpu , offload_optimizer=cpu , zero_init=1
+ 70.00GB | 0.25GB | offload_param=cpu , offload_optimizer=cpu , zero_init=0
+ 62.23GB | 2.84GB | offload_param=none, offload_optimizer=cpu , zero_init=1
+ 62.23GB | 2.84GB | offload_param=none, offload_optimizer=cpu , zero_init=0
+ 0.74GB | 23.58GB | offload_param=none, offload_optimizer=none, zero_init=1
+ 31.11GB | 23.58GB | offload_param=none, offload_optimizer=none, zero_init=0
+
+```
+
+所以,您需要2个32GB或更高的GPU,且不进行CPU卸载。
+
+如需了解更多信息,请参阅[内存估算器](https://deepspeed.readthedocs.io/en/latest/memory.html)。
+
+
+
+### 归档Issues
+
+请按照以下步骤提交问题,以便我们能够迅速找到问题并帮助您解除工作阻塞。
+
+在您的报告中,请始终包括以下内容:
+
+1. 完整的Deepspeed配置文件
+2. 如果使用了[`Trainer`],则包括命令行参数;如果自己编写了Trainer设置,则包括[`TrainingArguments`]参数。请不要导出[`TrainingArguments`],因为它有几十个与问题无关的条目。
+3. 输出:
+
+ ```bash
+ python -c 'import torch; print(f"torch: {torch.__version__}")'
+ python -c 'import transformers; print(f"transformers: {transformers.__version__}")'
+ python -c 'import deepspeed; print(f"deepspeed: {deepspeed.__version__}")'
+ ```
+
+4. 如果可能,请包含一个Google Colab notebook链接,我们可以使用它来重现问题。您可以使用这个[notebook](https://github.com/stas00/porting/blob/master/transformers/deepspeed/DeepSpeed_on_colab_CLI.ipynb)作为起点。
+5. 除非不可能,否则请始终使用标准数据集,而不是自定义数据集。
+6. 如果可能,尝试使用现有[示例](https://github.com/huggingface/transformers/tree/main/examples/pytorch)之一来重现问题。
+
+需要考虑的因素:
+
+- Deepspeed通常不是问题的原因。
+
+ 一些已提交的问题被证明与Deepspeed无关。也就是说,一旦将Deepspeed从设置中移除,问题仍然存在。
+
+ 因此,如果问题明显与DeepSpeed相关,例如您可以看到有一个异常并且可以看到DeepSpeed模块涉及其中,请先重新测试没有DeepSpeed的设置。只有当问题仍然存在时,才向Deepspeed提供所有必需的细节。
+
+- 如果您明确问题是在Deepspeed核心中而不是集成部分,请直接向[Deepspeed](https://github.com/microsoft/DeepSpeed/)提交问题。如果您不确定,请不要担心,无论使用哪个issue跟踪问题都可以,一旦您发布问题,我们会弄清楚并将其重定向到另一个issue跟踪(如果需要的话)。
+
+
+
+### Troubleshooting
+
+#### 启动时`deepspeed`进程被终止,没有回溯
+
+如果启动时`deepspeed`进程被终止,没有回溯,这通常意味着程序尝试分配的CPU内存超过了系统的限制或进程被允许分配的内存,操作系统内核杀死了该进程。这是因为您的配置文件很可能将`offload_optimizer`或`offload_param`或两者都配置为卸载到`cpu`。如果您有NVMe,可以尝试在ZeRO-3下卸载到NVMe。这里是如何[估计特定模型所需的内存](https://deepspeed.readthedocs.io/en/latest/memory.html)。
+
+#### 训练和/或评估/预测loss为`NaN`
+
+这种情况通常发生在使用bf16混合精度模式预训练的模型试图在fp16(带或不带混合精度)下使用时。大多数在TPU上训练的模型以及由谷歌发布的模型都属于这个类别(例如,几乎所有基于t5的模型)。在这种情况下,解决方案是要么使用fp32,要么在支持的情况下使用bf16(如TPU、Ampere GPU或更新的版本)。
+
+另一个问题可能与使用fp16有关。当您配置此部分时:
+
+```json
+{
+ "fp16": {
+ "enabled": "auto",
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ }
+}
+```
+
+并且您在日志中看到Deepspeed报告`OVERFLOW`如下
+
+```
+0%| | 0/189 [00:00=4.28`开始,如果没有明确指定`synced_gpus`,检测到这些条件后它将自动设置为`True`。但如果您需要覆盖`synced_gpus`的值,仍然可以这样做。
+
+
+
+## 测试 DeepSpeed 集成
+
+如果您提交了一个涉及DeepSpeed集成的PR,请注意我们的CircleCI PR CI设置没有GPU,因此我们只在另一个CI夜间运行需要GPU的测试。因此,如果您在PR中获得绿色的CI报告,并不意味着DeepSpeed测试通过。
+
+要运行DeepSpeed测试,请至少运行以下命令:
+
+```bash
+RUN_SLOW=1 pytest tests/deepspeed/test_deepspeed.py
+```
+
+如果你更改了任何模型或PyTorch示例代码,请同时运行多模型测试。以下将运行所有DeepSpeed测试:
+
+```bash
+RUN_SLOW=1 pytest tests/deepspeed
+```
+
+## 主要的DeepSpeed资源
+
+- [项目GitHub](https://github.com/microsoft/deepspeed)
+- [使用文档](https://www.deepspeed.ai/getting-started/)
+- [API文档](https://deepspeed.readthedocs.io/en/latest/index.html)
+- [博客文章](https://www.microsoft.com/en-us/research/search/?q=deepspeed)
+
+论文:
+
+- [ZeRO: Memory Optimizations Toward Training Trillion Parameter Models](https://arxiv.org/abs/1910.02054)
+- [ZeRO-Offload: Democratizing Billion-Scale Model Training](https://arxiv.org/abs/2101.06840)
+- [ZeRO-Infinity: Breaking the GPU Memory Wall for Extreme Scale Deep Learning](https://arxiv.org/abs/2104.07857)
+
+最后,请记住,HuggingFace [`Trainer`]仅集成了DeepSpeed,因此如果您在使用DeepSpeed时遇到任何问题或疑问,请在[DeepSpeed GitHub](https://github.com/microsoft/DeepSpeed/issues)上提交一个issue。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/feature_extractor.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/feature_extractor.md
new file mode 100644
index 0000000000000000000000000000000000000000..f3b65ebf9d66cc39ff21d823bf515eb281472889
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/feature_extractor.md
@@ -0,0 +1,39 @@
+
+
+# Feature Extractor
+
+Feature Extractor负责为音频或视觉模型准备输入特征。这包括从序列中提取特征,例如,对音频文件进行预处理以生成Log-Mel频谱特征,以及从图像中提取特征,例如,裁剪图像文件,同时还包括填充、归一化和转换为NumPy、PyTorch和TensorFlow张量。
+
+
+## FeatureExtractionMixin
+
+[[autodoc]] feature_extraction_utils.FeatureExtractionMixin
+ - from_pretrained
+ - save_pretrained
+
+## SequenceFeatureExtractor
+
+[[autodoc]] SequenceFeatureExtractor
+ - pad
+
+## BatchFeature
+
+[[autodoc]] BatchFeature
+
+## ImageFeatureExtractionMixin
+
+[[autodoc]] image_utils.ImageFeatureExtractionMixin
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/image_processor.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/image_processor.md
new file mode 100644
index 0000000000000000000000000000000000000000..035afa55348a26671d2b3ae82f4421eb0a01f09d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/image_processor.md
@@ -0,0 +1,34 @@
+
+
+# Image Processor
+
+Image processor负责为视觉模型准备输入特征并后期处理处理它们的输出。这包括诸如调整大小、归一化和转换为PyTorch、TensorFlow、Flax和NumPy张量等转换。它还可能包括特定于模型的后期处理,例如将logits转换为分割掩码。
+
+
+## ImageProcessingMixin
+
+[[autodoc]] image_processing_utils.ImageProcessingMixin
+ - from_pretrained
+ - save_pretrained
+
+## BatchFeature
+
+[[autodoc]] BatchFeature
+
+## BaseImageProcessor
+
+[[autodoc]] image_processing_utils.BaseImageProcessor
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/keras_callbacks.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/keras_callbacks.md
new file mode 100644
index 0000000000000000000000000000000000000000..1eea2eb998162c7af06863700ef2a388a7ea1c53
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/keras_callbacks.md
@@ -0,0 +1,27 @@
+
+
+# Keras callbacks
+
+在Keras中训练Transformers模型时,有一些库特定的callbacks函数可用于自动执行常见任务:
+
+## KerasMetricCallback
+
+[[autodoc]] KerasMetricCallback
+
+## PushToHubCallback
+
+[[autodoc]] PushToHubCallback
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/logging.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/logging.md
new file mode 100644
index 0000000000000000000000000000000000000000..6116e4962e6a33e65672615b4bd13661ae748776
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/logging.md
@@ -0,0 +1,107 @@
+
+
+# Logging
+
+🤗 Transformers拥有一个集中式的日志系统,因此您可以轻松设置库输出的日志详细程度。
+
+当前库的默认日志详细程度为`WARNING`。
+
+要更改日志详细程度,只需使用其中一个直接的setter。例如,以下是如何将日志详细程度更改为INFO级别的方法:
+
+```python
+import transformers
+
+transformers.logging.set_verbosity_info()
+```
+
+您还可以使用环境变量`TRANSFORMERS_VERBOSITY`来覆盖默认的日志详细程度。您可以将其设置为以下级别之一:`debug`、`info`、`warning`、`error`、`critical`。例如:
+
+```bash
+TRANSFORMERS_VERBOSITY=error ./myprogram.py
+```
+
+此外,通过将环境变量`TRANSFORMERS_NO_ADVISORY_WARNINGS`设置为`true`(如*1*),可以禁用一些`warnings`。这将禁用[`logger.warning_advice`]记录的任何警告。例如:
+
+```bash
+TRANSFORMERS_NO_ADVISORY_WARNINGS=1 ./myprogram.py
+```
+
+以下是如何在您自己的模块或脚本中使用与库相同的logger的示例:
+
+```python
+from transformers.utils import logging
+
+logging.set_verbosity_info()
+logger = logging.get_logger("transformers")
+logger.info("INFO")
+logger.warning("WARN")
+```
+
+
+此日志模块的所有方法都在下面进行了记录,主要的方法包括 [`logging.get_verbosity`] 用于获取logger当前输出日志详细程度的级别和 [`logging.set_verbosity`] 用于将详细程度设置为您选择的级别。按照顺序(从最不详细到最详细),这些级别(及其相应的整数值)为:
+
+- `transformers.logging.CRITICAL` 或 `transformers.logging.FATAL`(整数值,50):仅报告最关键的errors。
+- `transformers.logging.ERROR`(整数值,40):仅报告errors。
+- `transformers.logging.WARNING` 或 `transformers.logging.WARN`(整数值,30):仅报告error和warnings。这是库使用的默认级别。
+- `transformers.logging.INFO`(整数值,20):报告error、warnings和基本信息。
+- `transformers.logging.DEBUG`(整数值,10):报告所有信息。
+
+默认情况下,将在模型下载期间显示`tqdm`进度条。[`logging.disable_progress_bar`] 和 [`logging.enable_progress_bar`] 可用于禁止或启用此行为。
+
+## `logging` vs `warnings`
+
+Python有两个经常一起使用的日志系统:如上所述的`logging`,和对特定buckets中的警告进行进一步分类的`warnings`,例如,`FutureWarning`用于输出已经被弃用的功能或路径,`DeprecationWarning`用于指示即将被弃用的内容。
+
+我们在`transformers`库中同时使用这两个系统。我们利用并调整了`logging`的`captureWarning`方法,以便通过上面的详细程度setters来管理这些警告消息。
+
+对于库的开发人员,这意味着什么呢?我们应该遵循以下启发法则:
+- 库的开发人员和依赖于`transformers`的库应优先使用`warnings`
+- `logging`应该用于在日常项目中经常使用它的用户
+
+以下是`captureWarnings`方法的参考。
+
+[[autodoc]] logging.captureWarnings
+
+## Base setters
+
+[[autodoc]] logging.set_verbosity_error
+
+[[autodoc]] logging.set_verbosity_warning
+
+[[autodoc]] logging.set_verbosity_info
+
+[[autodoc]] logging.set_verbosity_debug
+
+## Other functions
+
+[[autodoc]] logging.get_verbosity
+
+[[autodoc]] logging.set_verbosity
+
+[[autodoc]] logging.get_logger
+
+[[autodoc]] logging.enable_default_handler
+
+[[autodoc]] logging.disable_default_handler
+
+[[autodoc]] logging.enable_explicit_format
+
+[[autodoc]] logging.reset_format
+
+[[autodoc]] logging.enable_progress_bar
+
+[[autodoc]] logging.disable_progress_bar
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/model.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/model.md
new file mode 100644
index 0000000000000000000000000000000000000000..6c0ee3e2b2c097e0be826b4f5fe42d8b4ce1c261
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/model.md
@@ -0,0 +1,137 @@
+
+
+# 模型
+
+基类 [`PreTrainedModel`]、[`TFPreTrainedModel`] 和 [`FlaxPreTrainedModel`] 实现了从本地文件或目录加载/保存模型的常用方法,或者从库上提供的预训练模型配置(从 HuggingFace 的 AWS S3 存储库下载)加载模型。
+
+[`PreTrainedModel`] 和 [`TFPreTrainedModel`] 还实现了一些所有模型共有的方法:
+
+- 在向量词嵌入增加新词汇时调整输入标记(token)的大小
+- 对模型的注意力头进行修剪。
+
+其他的通用方法在 [`~modeling_utils.ModuleUtilsMixin`](用于 PyTorch 模型)和 [`~modeling_tf_utils.TFModuleUtilsMixin`](用于 TensorFlow 模型)中定义;文本生成方面的方法则定义在 [`~generation.GenerationMixin`](用于 PyTorch 模型)、[`~generation.TFGenerationMixin`](用于 TensorFlow 模型)和 [`~generation.FlaxGenerationMixin`](用于 Flax/JAX 模型)中。
+
+## PreTrainedModel
+
+[[autodoc]] PreTrainedModel
+ - push_to_hub
+ - all
+
+
+
+当传递 `output_hidden_states=True` 时,您可能希望 `outputs.hidden_states[-1]` 与 `outputs.last_hidden_states` 完全匹配。然而,这并不总是成立。一些模型在返回最后的 hidden state时对其应用归一化或其他后续处理。
+
+
+
+
+您可以像往常一样访问每个属性,如果模型未返回该属性,您将得到 `None`。在这里,例如,`outputs.loss` 是模型计算的损失,而 `outputs.attentions` 是 `None`。
+
+当将我们的 `outputs` 对象视为元组时,它仅考虑那些没有 `None` 值的属性。例如这里它有两个元素,`loss` 和 `logits`,所以
+
+```python
+outputs[:2]
+```
+
+将返回元组 `(outputs.loss, outputs.logits)`。
+
+将我们的 `outputs` 对象视为字典时,它仅考虑那些没有 `None` 值的属性。例如在这里它有两个键,分别是 `loss` 和 `logits`。
+
+我们在这里记录了被多个类型模型使用的通用模型输出。特定输出类型在其相应的模型页面上有文档。
+
+## ModelOutput
+
+[[autodoc]] utils.ModelOutput
+ - to_tuple
+
+## BaseModelOutput
+
+[[autodoc]] modeling_outputs.BaseModelOutput
+
+## BaseModelOutputWithPooling
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPooling
+
+## BaseModelOutputWithCrossAttentions
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithCrossAttentions
+
+## BaseModelOutputWithPoolingAndCrossAttentions
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPoolingAndCrossAttentions
+
+## BaseModelOutputWithPast
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPast
+
+## BaseModelOutputWithPastAndCrossAttentions
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPastAndCrossAttentions
+
+## Seq2SeqModelOutput
+
+[[autodoc]] modeling_outputs.Seq2SeqModelOutput
+
+## CausalLMOutput
+
+[[autodoc]] modeling_outputs.CausalLMOutput
+
+## CausalLMOutputWithCrossAttentions
+
+[[autodoc]] modeling_outputs.CausalLMOutputWithCrossAttentions
+
+## CausalLMOutputWithPast
+
+[[autodoc]] modeling_outputs.CausalLMOutputWithPast
+
+## MaskedLMOutput
+
+[[autodoc]] modeling_outputs.MaskedLMOutput
+
+## Seq2SeqLMOutput
+
+[[autodoc]] modeling_outputs.Seq2SeqLMOutput
+
+## NextSentencePredictorOutput
+
+[[autodoc]] modeling_outputs.NextSentencePredictorOutput
+
+## SequenceClassifierOutput
+
+[[autodoc]] modeling_outputs.SequenceClassifierOutput
+
+## Seq2SeqSequenceClassifierOutput
+
+[[autodoc]] modeling_outputs.Seq2SeqSequenceClassifierOutput
+
+## MultipleChoiceModelOutput
+
+[[autodoc]] modeling_outputs.MultipleChoiceModelOutput
+
+## TokenClassifierOutput
+
+[[autodoc]] modeling_outputs.TokenClassifierOutput
+
+## QuestionAnsweringModelOutput
+
+[[autodoc]] modeling_outputs.QuestionAnsweringModelOutput
+
+## Seq2SeqQuestionAnsweringModelOutput
+
+[[autodoc]] modeling_outputs.Seq2SeqQuestionAnsweringModelOutput
+
+## Seq2SeqSpectrogramOutput
+
+[[autodoc]] modeling_outputs.Seq2SeqSpectrogramOutput
+
+## SemanticSegmenterOutput
+
+[[autodoc]] modeling_outputs.SemanticSegmenterOutput
+
+## ImageClassifierOutput
+
+[[autodoc]] modeling_outputs.ImageClassifierOutput
+
+## ImageClassifierOutputWithNoAttention
+
+[[autodoc]] modeling_outputs.ImageClassifierOutputWithNoAttention
+
+## DepthEstimatorOutput
+
+[[autodoc]] modeling_outputs.DepthEstimatorOutput
+
+## Wav2Vec2BaseModelOutput
+
+[[autodoc]] modeling_outputs.Wav2Vec2BaseModelOutput
+
+## XVectorOutput
+
+[[autodoc]] modeling_outputs.XVectorOutput
+
+## Seq2SeqTSModelOutput
+
+[[autodoc]] modeling_outputs.Seq2SeqTSModelOutput
+
+## Seq2SeqTSPredictionOutput
+
+[[autodoc]] modeling_outputs.Seq2SeqTSPredictionOutput
+
+## SampleTSPredictionOutput
+
+[[autodoc]] modeling_outputs.SampleTSPredictionOutput
+
+## TFBaseModelOutput
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutput
+
+## TFBaseModelOutputWithPooling
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPooling
+
+## TFBaseModelOutputWithPoolingAndCrossAttentions
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPoolingAndCrossAttentions
+
+## TFBaseModelOutputWithPast
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPast
+
+## TFBaseModelOutputWithPastAndCrossAttentions
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPastAndCrossAttentions
+
+## TFSeq2SeqModelOutput
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqModelOutput
+
+## TFCausalLMOutput
+
+[[autodoc]] modeling_tf_outputs.TFCausalLMOutput
+
+## TFCausalLMOutputWithCrossAttentions
+
+[[autodoc]] modeling_tf_outputs.TFCausalLMOutputWithCrossAttentions
+
+## TFCausalLMOutputWithPast
+
+[[autodoc]] modeling_tf_outputs.TFCausalLMOutputWithPast
+
+## TFMaskedLMOutput
+
+[[autodoc]] modeling_tf_outputs.TFMaskedLMOutput
+
+## TFSeq2SeqLMOutput
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqLMOutput
+
+## TFNextSentencePredictorOutput
+
+[[autodoc]] modeling_tf_outputs.TFNextSentencePredictorOutput
+
+## TFSequenceClassifierOutput
+
+[[autodoc]] modeling_tf_outputs.TFSequenceClassifierOutput
+
+## TFSeq2SeqSequenceClassifierOutput
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqSequenceClassifierOutput
+
+## TFMultipleChoiceModelOutput
+
+[[autodoc]] modeling_tf_outputs.TFMultipleChoiceModelOutput
+
+## TFTokenClassifierOutput
+
+[[autodoc]] modeling_tf_outputs.TFTokenClassifierOutput
+
+## TFQuestionAnsweringModelOutput
+
+[[autodoc]] modeling_tf_outputs.TFQuestionAnsweringModelOutput
+
+## TFSeq2SeqQuestionAnsweringModelOutput
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqQuestionAnsweringModelOutput
+
+## FlaxBaseModelOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutput
+
+## FlaxBaseModelOutputWithPast
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutputWithPast
+
+## FlaxBaseModelOutputWithPooling
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutputWithPooling
+
+## FlaxBaseModelOutputWithPastAndCrossAttentions
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutputWithPastAndCrossAttentions
+
+## FlaxSeq2SeqModelOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqModelOutput
+
+## FlaxCausalLMOutputWithCrossAttentions
+
+[[autodoc]] modeling_flax_outputs.FlaxCausalLMOutputWithCrossAttentions
+
+## FlaxMaskedLMOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxMaskedLMOutput
+
+## FlaxSeq2SeqLMOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqLMOutput
+
+## FlaxNextSentencePredictorOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxNextSentencePredictorOutput
+
+## FlaxSequenceClassifierOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxSequenceClassifierOutput
+
+## FlaxSeq2SeqSequenceClassifierOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqSequenceClassifierOutput
+
+## FlaxMultipleChoiceModelOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxMultipleChoiceModelOutput
+
+## FlaxTokenClassifierOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxTokenClassifierOutput
+
+## FlaxQuestionAnsweringModelOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxQuestionAnsweringModelOutput
+
+## FlaxSeq2SeqQuestionAnsweringModelOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqQuestionAnsweringModelOutput
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/pipelines.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/pipelines.md
new file mode 100644
index 0000000000000000000000000000000000000000..bc16709d8b483271ba7df7b2e4afded833e58244
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/pipelines.md
@@ -0,0 +1,478 @@
+
+
+# Pipelines
+
+pipelines是使用模型进行推理的一种简单方法。这些pipelines是抽象了库中大部分复杂代码的对象,提供了一个专用于多个任务的简单API,包括专名识别、掩码语言建模、情感分析、特征提取和问答等。请参阅[任务摘要](../task_summary)以获取使用示例。
+
+有两种pipelines抽象类需要注意:
+
+- [`pipeline`],它是封装所有其他pipelines的最强大的对象。
+- 针对特定任务pipelines,适用于[音频](#audio)、[计算机视觉](#computer-vision)、[自然语言处理](#natural-language-processing)和[多模态](#multimodal)任务。
+
+## pipeline抽象类
+
+*pipeline*抽象类是对所有其他可用pipeline的封装。它可以像任何其他pipeline一样实例化,但进一步提供额外的便利性。
+
+简单调用一个项目:
+
+
+```python
+>>> pipe = pipeline("text-classification")
+>>> pipe("This restaurant is awesome")
+[{'label': 'POSITIVE', 'score': 0.9998743534088135}]
+```
+
+如果您想使用 [hub](https://huggingface.co) 上的特定模型,可以忽略任务,如果hub上的模型已经定义了该任务:
+
+```python
+>>> pipe = pipeline(model="FacebookAI/roberta-large-mnli")
+>>> pipe("This restaurant is awesome")
+[{'label': 'NEUTRAL', 'score': 0.7313136458396912}]
+```
+
+要在多个项目上调用pipeline,可以使用*列表*调用它。
+
+```python
+>>> pipe = pipeline("text-classification")
+>>> pipe(["This restaurant is awesome", "This restaurant is awful"])
+[{'label': 'POSITIVE', 'score': 0.9998743534088135},
+ {'label': 'NEGATIVE', 'score': 0.9996669292449951}]
+```
+
+为了遍历整个数据集,建议直接使用 `dataset`。这意味着您不需要一次性分配整个数据集,也不需要自己进行批处理。这应该与GPU上的自定义循环一样快。如果不是,请随时提出issue。
+
+```python
+import datasets
+from transformers import pipeline
+from transformers.pipelines.pt_utils import KeyDataset
+from tqdm.auto import tqdm
+
+pipe = pipeline("automatic-speech-recognition", model="facebook/wav2vec2-base-960h", device=0)
+dataset = datasets.load_dataset("superb", name="asr", split="test")
+
+# KeyDataset (only *pt*) will simply return the item in the dict returned by the dataset item
+# as we're not interested in the *target* part of the dataset. For sentence pair use KeyPairDataset
+for out in tqdm(pipe(KeyDataset(dataset, "file"))):
+ print(out)
+ # {"text": "NUMBER TEN FRESH NELLY IS WAITING ON YOU GOOD NIGHT HUSBAND"}
+ # {"text": ....}
+ # ....
+```
+
+为了方便使用,也可以使用生成器:
+
+
+```python
+from transformers import pipeline
+
+pipe = pipeline("text-classification")
+
+
+def data():
+ while True:
+ # This could come from a dataset, a database, a queue or HTTP request
+ # in a server
+ # Caveat: because this is iterative, you cannot use `num_workers > 1` variable
+ # to use multiple threads to preprocess data. You can still have 1 thread that
+ # does the preprocessing while the main runs the big inference
+ yield "This is a test"
+
+
+for out in pipe(data()):
+ print(out)
+ # {"text": "NUMBER TEN FRESH NELLY IS WAITING ON YOU GOOD NIGHT HUSBAND"}
+ # {"text": ....}
+ # ....
+```
+
+[[autodoc]] pipeline
+
+## Pipeline batching
+
+所有pipeline都可以使用批处理。这将在pipeline使用其流处理功能时起作用(即传递列表或 `Dataset` 或 `generator` 时)。
+
+```python
+from transformers import pipeline
+from transformers.pipelines.pt_utils import KeyDataset
+import datasets
+
+dataset = datasets.load_dataset("imdb", name="plain_text", split="unsupervised")
+pipe = pipeline("text-classification", device=0)
+for out in pipe(KeyDataset(dataset, "text"), batch_size=8, truncation="only_first"):
+ print(out)
+ # [{'label': 'POSITIVE', 'score': 0.9998743534088135}]
+ # Exactly the same output as before, but the content are passed
+ # as batches to the model
+```
+
+
+
+然而,这并不自动意味着性能提升。它可能是一个10倍的加速或5倍的减速,具体取决于硬件、数据和实际使用的模型。
+
+主要是加速的示例:
+
+
+
+```python
+from transformers import pipeline
+from torch.utils.data import Dataset
+from tqdm.auto import tqdm
+
+pipe = pipeline("text-classification", device=0)
+
+
+class MyDataset(Dataset):
+ def __len__(self):
+ return 5000
+
+ def __getitem__(self, i):
+ return "This is a test"
+
+
+dataset = MyDataset()
+
+for batch_size in [1, 8, 64, 256]:
+ print("-" * 30)
+ print(f"Streaming batch_size={batch_size}")
+ for out in tqdm(pipe(dataset, batch_size=batch_size), total=len(dataset)):
+ pass
+```
+
+```
+# On GTX 970
+------------------------------
+Streaming no batching
+100%|██████████████████████████████████████████████████████████████████████| 5000/5000 [00:26<00:00, 187.52it/s]
+------------------------------
+Streaming batch_size=8
+100%|█████████████████████████████████████████████████████████████████████| 5000/5000 [00:04<00:00, 1205.95it/s]
+------------------------------
+Streaming batch_size=64
+100%|█████████████████████████████████████████████████████████████████████| 5000/5000 [00:02<00:00, 2478.24it/s]
+------------------------------
+Streaming batch_size=256
+100%|█████████████████████████████████████████████████████████████████████| 5000/5000 [00:01<00:00, 2554.43it/s]
+(diminishing returns, saturated the GPU)
+```
+
+主要是减速的示例:
+
+```python
+class MyDataset(Dataset):
+ def __len__(self):
+ return 5000
+
+ def __getitem__(self, i):
+ if i % 64 == 0:
+ n = 100
+ else:
+ n = 1
+ return "This is a test" * n
+```
+
+与其他句子相比,这是一个非常长的句子。在这种情况下,**整个**批次将需要400个tokens的长度,因此整个批次将是 [64, 400] 而不是 [64, 4],从而导致较大的减速。更糟糕的是,在更大的批次上,程序会崩溃。
+
+```
+------------------------------
+Streaming no batching
+100%|█████████████████████████████████████████████████████████████████████| 1000/1000 [00:05<00:00, 183.69it/s]
+------------------------------
+Streaming batch_size=8
+100%|█████████████████████████████████████████████████████████████████████| 1000/1000 [00:03<00:00, 265.74it/s]
+------------------------------
+Streaming batch_size=64
+100%|██████████████████████████████████████████████████████████████████████| 1000/1000 [00:26<00:00, 37.80it/s]
+------------------------------
+Streaming batch_size=256
+ 0%| | 0/1000 [00:00
+ for out in tqdm(pipe(dataset, batch_size=256), total=len(dataset)):
+....
+ q = q / math.sqrt(dim_per_head) # (bs, n_heads, q_length, dim_per_head)
+RuntimeError: CUDA out of memory. Tried to allocate 376.00 MiB (GPU 0; 3.95 GiB total capacity; 1.72 GiB already allocated; 354.88 MiB free; 2.46 GiB reserved in total by PyTorch)
+```
+
+对于这个问题,没有好的(通用)解决方案,效果可能因您的用例而异。经验法则如下:
+
+对于用户,一个经验法则是:
+
+- **使用硬件测量负载性能。测量、测量、再测量。真实的数字是唯一的方法。**
+- 如果受到延迟的限制(进行推理的实时产品),不要进行批处理。
+- 如果使用CPU,不要进行批处理。
+- 如果您在GPU上处理的是吞吐量(您希望在大量静态数据上运行模型),则:
+ - 如果对序列长度的大小没有概念("自然"数据),默认情况下不要进行批处理,进行测试并尝试逐渐添加,添加OOM检查以在失败时恢复(如果您不能控制序列长度,它将在某些时候失败)。
+ - 如果您的序列长度非常规律,那么批处理更有可能非常有趣,进行测试并推动它,直到出现OOM。
+ - GPU越大,批处理越有可能变得更有趣
+- 一旦启用批处理,确保能够很好地处理OOM。
+
+## Pipeline chunk batching
+
+`zero-shot-classification` 和 `question-answering` 在某种意义上稍微特殊,因为单个输入可能会导致模型的多次前向传递。在正常情况下,这将导致 `batch_size` 参数的问题。
+
+为了规避这个问题,这两个pipeline都有点特殊,它们是 `ChunkPipeline` 而不是常规的 `Pipeline`。简而言之:
+
+
+```python
+preprocessed = pipe.preprocess(inputs)
+model_outputs = pipe.forward(preprocessed)
+outputs = pipe.postprocess(model_outputs)
+```
+
+现在变成:
+
+
+```python
+all_model_outputs = []
+for preprocessed in pipe.preprocess(inputs):
+ model_outputs = pipe.forward(preprocessed)
+ all_model_outputs.append(model_outputs)
+outputs = pipe.postprocess(all_model_outputs)
+```
+
+这对您的代码应该是非常直观的,因为pipeline的使用方式是相同的。
+
+这是一个简化的视图,因为Pipeline可以自动处理批次!这意味着您不必担心您的输入实际上会触发多少次前向传递,您可以独立于输入优化 `batch_size`。前面部分的注意事项仍然适用。
+
+## Pipeline自定义
+
+如果您想要重载特定的pipeline。
+
+请随时为您手头的任务创建一个issue,Pipeline的目标是易于使用并支持大多数情况,因此 `transformers` 可能支持您的用例。
+
+如果您想简单地尝试一下,可以:
+
+- 继承您选择的pipeline
+
+```python
+class MyPipeline(TextClassificationPipeline):
+ def postprocess():
+ # Your code goes here
+ scores = scores * 100
+ # And here
+
+
+my_pipeline = MyPipeline(model=model, tokenizer=tokenizer, ...)
+# or if you use *pipeline* function, then:
+my_pipeline = pipeline(model="xxxx", pipeline_class=MyPipeline)
+```
+
+这样就可以让您编写所有想要的自定义代码。
+
+
+## 实现一个pipeline
+
+[实现一个新的pipeline](../add_new_pipeline)
+
+## 音频
+
+可用于音频任务的pipeline包括以下几种。
+
+### AudioClassificationPipeline
+
+[[autodoc]] AudioClassificationPipeline
+ - __call__
+ - all
+
+### AutomaticSpeechRecognitionPipeline
+
+[[autodoc]] AutomaticSpeechRecognitionPipeline
+ - __call__
+ - all
+
+### TextToAudioPipeline
+
+[[autodoc]] TextToAudioPipeline
+ - __call__
+ - all
+
+
+### ZeroShotAudioClassificationPipeline
+
+[[autodoc]] ZeroShotAudioClassificationPipeline
+ - __call__
+ - all
+
+## 计算机视觉
+
+可用于计算机视觉任务的pipeline包括以下几种。
+
+### DepthEstimationPipeline
+[[autodoc]] DepthEstimationPipeline
+ - __call__
+ - all
+
+### ImageClassificationPipeline
+
+[[autodoc]] ImageClassificationPipeline
+ - __call__
+ - all
+
+### ImageSegmentationPipeline
+
+[[autodoc]] ImageSegmentationPipeline
+ - __call__
+ - all
+
+### ImageToImagePipeline
+
+[[autodoc]] ImageToImagePipeline
+ - __call__
+ - all
+
+### ObjectDetectionPipeline
+
+[[autodoc]] ObjectDetectionPipeline
+ - __call__
+ - all
+
+### VideoClassificationPipeline
+
+[[autodoc]] VideoClassificationPipeline
+ - __call__
+ - all
+
+### ZeroShotImageClassificationPipeline
+
+[[autodoc]] ZeroShotImageClassificationPipeline
+ - __call__
+ - all
+
+### ZeroShotObjectDetectionPipeline
+
+[[autodoc]] ZeroShotObjectDetectionPipeline
+ - __call__
+ - all
+
+## 自然语言处理
+
+可用于自然语言处理任务的pipeline包括以下几种。
+
+### FillMaskPipeline
+
+[[autodoc]] FillMaskPipeline
+ - __call__
+ - all
+
+### NerPipeline
+
+[[autodoc]] NerPipeline
+
+See [`TokenClassificationPipeline`] for all details.
+
+### QuestionAnsweringPipeline
+
+[[autodoc]] QuestionAnsweringPipeline
+ - __call__
+ - all
+
+### SummarizationPipeline
+
+[[autodoc]] SummarizationPipeline
+ - __call__
+ - all
+
+### TableQuestionAnsweringPipeline
+
+[[autodoc]] TableQuestionAnsweringPipeline
+ - __call__
+
+### TextClassificationPipeline
+
+[[autodoc]] TextClassificationPipeline
+ - __call__
+ - all
+
+### TextGenerationPipeline
+
+[[autodoc]] TextGenerationPipeline
+ - __call__
+ - all
+
+### Text2TextGenerationPipeline
+
+[[autodoc]] Text2TextGenerationPipeline
+ - __call__
+ - all
+
+### TokenClassificationPipeline
+
+[[autodoc]] TokenClassificationPipeline
+ - __call__
+ - all
+
+### TranslationPipeline
+
+[[autodoc]] TranslationPipeline
+ - __call__
+ - all
+
+### ZeroShotClassificationPipeline
+
+[[autodoc]] ZeroShotClassificationPipeline
+ - __call__
+ - all
+
+## 多模态
+
+可用于多模态任务的pipeline包括以下几种。
+
+### DocumentQuestionAnsweringPipeline
+
+[[autodoc]] DocumentQuestionAnsweringPipeline
+ - __call__
+ - all
+
+### FeatureExtractionPipeline
+
+[[autodoc]] FeatureExtractionPipeline
+ - __call__
+ - all
+
+### ImageFeatureExtractionPipeline
+
+[[autodoc]] ImageFeatureExtractionPipeline
+ - __call__
+ - all
+
+### ImageToTextPipeline
+
+[[autodoc]] ImageToTextPipeline
+ - __call__
+ - all
+
+### ImageTextToTextPipeline
+
+[[autodoc]] ImageTextToTextPipeline
+ - __call__
+ - all
+
+### MaskGenerationPipeline
+
+[[autodoc]] MaskGenerationPipeline
+ - __call__
+ - all
+
+### VisualQuestionAnsweringPipeline
+
+[[autodoc]] VisualQuestionAnsweringPipeline
+ - __call__
+ - all
+
+## Parent class: `Pipeline`
+
+[[autodoc]] Pipeline
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/processors.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/processors.md
new file mode 100644
index 0000000000000000000000000000000000000000..60167e317adf90662ac1a04830781d88bce198c2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/processors.md
@@ -0,0 +1,146 @@
+
+
+# Processors
+
+在 Transformers 库中,processors可以有两种不同的含义:
+- 为多模态模型,例如[Wav2Vec2](../model_doc/wav2vec2)(语音和文本)或[CLIP](../model_doc/clip)(文本和视觉)预处理输入的对象
+- 在库的旧版本中用于预处理GLUE或SQUAD数据的已弃用对象。
+
+## 多模态processors
+
+任何多模态模型都需要一个对象来编码或解码将多个模态(包括文本、视觉和音频)组合在一起的数据。这由称为processors的对象处理,这些processors将两个或多个处理对象组合在一起,例如tokenizers(用于文本模态),image processors(用于视觉)和feature extractors(用于音频)。
+
+这些processors继承自以下实现保存和加载功能的基类:
+
+
+[[autodoc]] ProcessorMixin
+
+## 已弃用的processors
+
+所有processor都遵循与 [`~data.processors.utils.DataProcessor`] 相同的架构。processor返回一个 [`~data.processors.utils.InputExample`] 列表。这些 [`~data.processors.utils.InputExample`] 可以转换为 [`~data.processors.utils.InputFeatures`] 以供输送到模型。
+
+[[autodoc]] data.processors.utils.DataProcessor
+
+[[autodoc]] data.processors.utils.InputExample
+
+[[autodoc]] data.processors.utils.InputFeatures
+
+## GLUE
+
+[General Language Understanding Evaluation (GLUE)](https://gluebenchmark.com/) 是一个基准测试,评估模型在各种现有的自然语言理解任务上的性能。它与论文 [GLUE: A multi-task benchmark and analysis platform for natural language understanding](https://openreview.net/pdf?id=rJ4km2R5t7) 一同发布。
+
+该库为以下任务提供了总共10个processor:MRPC、MNLI、MNLI(mismatched)、CoLA、SST2、STSB、QQP、QNLI、RTE 和 WNLI。
+
+这些processor是:
+
+- [`~data.processors.utils.MrpcProcessor`]
+- [`~data.processors.utils.MnliProcessor`]
+- [`~data.processors.utils.MnliMismatchedProcessor`]
+- [`~data.processors.utils.Sst2Processor`]
+- [`~data.processors.utils.StsbProcessor`]
+- [`~data.processors.utils.QqpProcessor`]
+- [`~data.processors.utils.QnliProcessor`]
+- [`~data.processors.utils.RteProcessor`]
+- [`~data.processors.utils.WnliProcessor`]
+
+此外,还可以使用以下方法从数据文件加载值并将其转换为 [`~data.processors.utils.InputExample`] 列表。
+
+[[autodoc]] data.processors.glue.glue_convert_examples_to_features
+
+
+## XNLI
+
+[跨语言NLI语料库(XNLI)](https://www.nyu.edu/projects/bowman/xnli/) 是一个评估跨语言文本表示质量的基准测试。XNLI是一个基于[*MultiNLI*](http://www.nyu.edu/projects/bowman/multinli/)的众包数据集:”文本对“被标记为包含15种不同语言(包括英语等高资源语言和斯瓦希里语等低资源语言)的文本蕴涵注释。
+
+它与论文 [XNLI: Evaluating Cross-lingual Sentence Representations](https://arxiv.org/abs/1809.05053) 一同发布。
+
+该库提供了加载XNLI数据的processor:
+
+- [`~data.processors.utils.XnliProcessor`]
+
+请注意,由于测试集上有“gold”标签,因此评估是在测试集上进行的。
+
+使用这些processor的示例在 [run_xnli.py](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-classification/run_xnli.py) 脚本中提供。
+
+
+## SQuAD
+
+[斯坦福问答数据集(SQuAD)](https://rajpurkar.github.io/SQuAD-explorer//) 是一个评估模型在问答上性能的基准测试。有两个版本,v1.1 和 v2.0。第一个版本(v1.1)与论文 [SQuAD: 100,000+ Questions for Machine Comprehension of Text](https://arxiv.org/abs/1606.05250) 一同发布。第二个版本(v2.0)与论文 [Know What You Don't Know: Unanswerable Questions for SQuAD](https://arxiv.org/abs/1806.03822) 一同发布。
+
+该库为两个版本各自提供了一个processor:
+
+### Processors
+
+这两个processor是:
+
+- [`~data.processors.utils.SquadV1Processor`]
+- [`~data.processors.utils.SquadV2Processor`]
+
+它们都继承自抽象类 [`~data.processors.utils.SquadProcessor`]。
+
+[[autodoc]] data.processors.squad.SquadProcessor
+ - all
+
+此外,可以使用以下方法将 SQuAD 示例转换为可用作模型输入的 [`~data.processors.utils.SquadFeatures`]。
+
+[[autodoc]] data.processors.squad.squad_convert_examples_to_features
+
+
+这些processor以及前面提到的方法可以与包含数据的文件以及tensorflow_datasets包一起使用。下面给出了示例。
+
+
+### Example使用
+
+以下是使用processor以及使用数据文件的转换方法的示例:
+
+```python
+# Loading a V2 processor
+processor = SquadV2Processor()
+examples = processor.get_dev_examples(squad_v2_data_dir)
+
+# Loading a V1 processor
+processor = SquadV1Processor()
+examples = processor.get_dev_examples(squad_v1_data_dir)
+
+features = squad_convert_examples_to_features(
+ examples=examples,
+ tokenizer=tokenizer,
+ max_seq_length=max_seq_length,
+ doc_stride=args.doc_stride,
+ max_query_length=max_query_length,
+ is_training=not evaluate,
+)
+```
+
+使用 *tensorflow_datasets* 就像使用数据文件一样简单:
+
+```python
+# tensorflow_datasets only handle Squad V1.
+tfds_examples = tfds.load("squad")
+examples = SquadV1Processor().get_examples_from_dataset(tfds_examples, evaluate=evaluate)
+
+features = squad_convert_examples_to_features(
+ examples=examples,
+ tokenizer=tokenizer,
+ max_seq_length=max_seq_length,
+ doc_stride=args.doc_stride,
+ max_query_length=max_query_length,
+ is_training=not evaluate,
+)
+```
+
+另一个使用这些processor的示例在 [run_squad.py](https://github.com/huggingface/transformers/tree/main/examples/legacy/question-answering/run_squad.py) 脚本中提供。
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/quantization.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/quantization.md
new file mode 100644
index 0000000000000000000000000000000000000000..d303906a9956278a7b2144727496d5e23291e5e3
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/quantization.md
@@ -0,0 +1,572 @@
+
+
+# 量化 🤗 Transformers 模型
+
+## AWQ集成
+
+AWQ方法已经在[*AWQ: Activation-aware Weight Quantization for LLM Compression and Acceleration*论文](https://arxiv.org/abs/2306.00978)中引入。通过AWQ,您可以以4位精度运行模型,同时保留其原始性能(即没有性能降级),并具有比下面介绍的其他量化方法更出色的吞吐量 - 达到与纯`float16`推理相似的吞吐量。
+
+我们现在支持使用任何AWQ模型进行推理,这意味着任何人都可以加载和使用在Hub上推送或本地保存的AWQ权重。请注意,使用AWQ需要访问NVIDIA GPU。目前不支持CPU推理。
+
+
+### 量化一个模型
+
+我们建议用户查看生态系统中不同的现有工具,以使用AWQ算法对其模型进行量化,例如:
+
+- [`llm-awq`](https://github.com/mit-han-lab/llm-awq),来自MIT Han Lab
+- [`autoawq`](https://github.com/casper-hansen/AutoAWQ),来自[`casper-hansen`](https://github.com/casper-hansen)
+- Intel neural compressor,来自Intel - 通过[`optimum-intel`](https://huggingface.co/docs/optimum/main/en/intel/optimization_inc)使用
+
+生态系统中可能存在许多其他工具,请随时提出PR将它们添加到列表中。
+目前与🤗 Transformers的集成仅适用于使用`autoawq`和`llm-awq`量化后的模型。大多数使用`auto-awq`量化的模型可以在🤗 Hub的[`TheBloke`](https://huggingface.co/TheBloke)命名空间下找到,要使用`llm-awq`对模型进行量化,请参阅[`llm-awq`](https://github.com/mit-han-lab/llm-awq/)的示例文件夹中的[`convert_to_hf.py`](https://github.com/mit-han-lab/llm-awq/blob/main/examples/convert_to_hf.py)脚本。
+
+
+### 加载一个量化的模型
+
+您可以使用`from_pretrained`方法从Hub加载一个量化模型。通过检查模型配置文件(`configuration.json`)中是否存在`quantization_config`属性,来进行确认推送的权重是量化的。您可以通过检查字段`quantization_config.quant_method`来确认模型是否以AWQ格式进行量化,该字段应该设置为`"awq"`。请注意,为了性能原因,默认情况下加载模型将设置其他权重为`float16`。如果您想更改这种设置,可以通过将`torch_dtype`参数设置为`torch.float32`或`torch.bfloat16`。在下面的部分中,您可以找到一些示例片段和notebook。
+
+
+## 示例使用
+
+首先,您需要安装[`autoawq`](https://github.com/casper-hansen/AutoAWQ)库
+
+```bash
+pip install autoawq
+```
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_id = "TheBloke/zephyr-7B-alpha-AWQ"
+model = AutoModelForCausalLM.from_pretrained(model_id, device_map="cuda:0")
+```
+
+如果您首先将模型加载到CPU上,请确保在使用之前将其移动到GPU设备上。
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_id = "TheBloke/zephyr-7B-alpha-AWQ"
+model = AutoModelForCausalLM.from_pretrained(model_id).to("cuda:0")
+```
+
+### 结合 AWQ 和 Flash Attention
+
+您可以将AWQ量化与Flash Attention结合起来,得到一个既被量化又更快速的模型。只需使用`from_pretrained`加载模型,并传递`attn_implementation="flash_attention_2"`参数。
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained("TheBloke/zephyr-7B-alpha-AWQ", attn_implementation="flash_attention_2", device_map="cuda:0")
+```
+
+### 基准测试
+
+我们使用[`optimum-benchmark`](https://github.com/huggingface/optimum-benchmark)库进行了一些速度、吞吐量和延迟基准测试。
+
+请注意,在编写本文档部分时,可用的量化方法包括:`awq`、`gptq`和`bitsandbytes`。
+
+基准测试在一台NVIDIA-A100实例上运行,使用[`TheBloke/Mistral-7B-v0.1-AWQ`](https://huggingface.co/TheBloke/Mistral-7B-v0.1-AWQ)作为AWQ模型,[`TheBloke/Mistral-7B-v0.1-GPTQ`](https://huggingface.co/TheBloke/Mistral-7B-v0.1-GPTQ)作为GPTQ模型。我们还将其与`bitsandbytes`量化模型和`float16`模型进行了对比。以下是一些结果示例:
+
+
+
+
+
+
+
+
+
+
+
+目前,GPTQ量化仅适用于文本模型。此外,量化过程可能会花费很多时间,具体取决于硬件性能(175B模型在NVIDIA A100上需要4小时)。请在Hub上检查是否有模型的GPTQ量化版本。如果没有,您可以在GitHub上提交需求。
+
+
+### 推送量化模型到 🤗 Hub
+
+您可以使用`push_to_hub`将量化模型像任何模型一样推送到Hub。量化配置将与模型一起保存和推送。
+
+```python
+quantized_model.push_to_hub("opt-125m-gptq")
+tokenizer.push_to_hub("opt-125m-gptq")
+```
+
+如果您想在本地计算机上保存量化模型,您也可以使用`save_pretrained`来完成:
+
+```python
+quantized_model.save_pretrained("opt-125m-gptq")
+tokenizer.save_pretrained("opt-125m-gptq")
+```
+
+请注意,如果您量化模型时想使用`device_map`,请确保在保存之前将整个模型移动到您的GPU或CPU之一。
+
+```python
+quantized_model.to("cpu")
+quantized_model.save_pretrained("opt-125m-gptq")
+```
+
+### 从 🤗 Hub 加载一个量化模型
+
+您可以使用`from_pretrained`从Hub加载量化模型。
+请确保推送权重是量化的,检查模型配置对象中是否存在`quantization_config`属性。
+
+
+```python
+from transformers import AutoModelForCausalLM
+model = AutoModelForCausalLM.from_pretrained("{your_username}/opt-125m-gptq")
+```
+
+如果您想更快地加载模型,并且不需要分配比实际需要内存更多的内存,量化模型也使用`device_map`参数。确保您已安装`accelerate`库。
+
+```python
+from transformers import AutoModelForCausalLM
+model = AutoModelForCausalLM.from_pretrained("{your_username}/opt-125m-gptq", device_map="auto")
+```
+
+### Exllama内核加快推理速度
+
+保留格式:对于 4 位模型,您可以使用 exllama 内核来提高推理速度。默认情况下,它处于启用状态。您可以通过在 [`GPTQConfig`] 中传递 `use_exllama` 来更改此配置。这将覆盖存储在配置中的量化配置。请注意,您只能覆盖与内核相关的属性。此外,如果您想使用 exllama 内核,整个模型需要全部部署在 gpus 上。此外,您可以使用 版本 > 0.4.2 的 Auto-GPTQ 并传递 `device_map` = "cpu" 来执行 CPU 推理。对于 CPU 推理,您必须在 `GPTQConfig` 中传递 `use_exllama = False`。
+
+```py
+import torch
+gptq_config = GPTQConfig(bits=4)
+model = AutoModelForCausalLM.from_pretrained("{your_username}/opt-125m-gptq", device_map="auto", quantization_config=gptq_config)
+```
+
+随着 exllamav2 内核的发布,与 exllama 内核相比,您可以获得更快的推理速度。您只需在 [`GPTQConfig`] 中传递 `exllama_config={"version": 2}`:
+
+```py
+import torch
+gptq_config = GPTQConfig(bits=4, exllama_config={"version":2})
+model = AutoModelForCausalLM.from_pretrained("{your_username}/opt-125m-gptq", device_map="auto", quantization_config = gptq_config)
+```
+
+请注意,目前仅支持 4 位模型。此外,如果您正在使用 peft 对量化模型进行微调,建议禁用 exllama 内核。
+
+您可以在此找到这些内核的基准测试 [这里](https://github.com/huggingface/optimum/tree/main/tests/benchmark#gptq-benchmark)
+
+
+#### 微调一个量化模型
+
+在Hugging Face生态系统的官方支持下,您可以使用GPTQ进行量化后的模型进行微调。
+请查看`peft`库了解更多详情。
+
+### 示例演示
+
+请查看 Google Colab [notebook](https://colab.research.google.com/drive/1_TIrmuKOFhuRRiTWN94ilkUFu6ZX4ceb?usp=sharing),了解如何使用GPTQ量化您的模型以及如何使用peft微调量化模型。
+
+### GPTQConfig
+
+[[autodoc]] GPTQConfig
+
+
+## `bitsandbytes` 集成
+
+🤗 Transformers 与 `bitsandbytes` 上最常用的模块紧密集成。您可以使用几行代码以 8 位精度加载您的模型。
+自bitsandbytes的0.37.0版本发布以来,大多数GPU硬件都支持这一点。
+
+在[LLM.int8()](https://arxiv.org/abs/2208.07339)论文中了解更多关于量化方法的信息,或者在[博客文章](https://huggingface.co/blog/hf-bitsandbytes-integration)中了解关于合作的更多信息。
+
+自其“0.39.0”版本发布以来,您可以使用FP4数据类型,通过4位量化加载任何支持“device_map”的模型。
+
+如果您想量化自己的 pytorch 模型,请查看 🤗 Accelerate 的[文档](https://huggingface.co/docs/accelerate/main/en/usage_guides/quantization)。
+
+以下是您可以使用“bitsandbytes”集成完成的事情
+
+### 通用用法
+
+只要您的模型支持使用 🤗 Accelerate 进行加载并包含 `torch.nn.Linear` 层,您可以在调用 [`~PreTrainedModel.from_pretrained`] 方法时使用 `load_in_8bit` 或 `load_in_4bit` 参数来量化模型。这也应该适用于任何模态。
+
+```python
+from transformers import AutoModelForCausalLM
+
+model_8bit = AutoModelForCausalLM.from_pretrained("facebook/opt-350m", load_in_8bit=True)
+model_4bit = AutoModelForCausalLM.from_pretrained("facebook/opt-350m", load_in_4bit=True)
+```
+
+默认情况下,所有其他模块(例如 `torch.nn.LayerNorm`)将被转换为 `torch.float16` 类型。但如果您想更改它们的 `dtype`,可以重载 `torch_dtype` 参数:
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM
+
+>>> model_8bit = AutoModelForCausalLM.from_pretrained("facebook/opt-350m", load_in_8bit=True, torch_dtype=torch.float32)
+>>> model_8bit.model.decoder.layers[-1].final_layer_norm.weight.dtype
+torch.float32
+```
+
+
+### FP4 量化
+
+#### 要求
+
+确保在运行以下代码段之前已完成以下要求:
+
+- 最新版本 `bitsandbytes` 库
+`pip install bitsandbytes>=0.39.0`
+
+- 安装最新版本 `accelerate`
+`pip install --upgrade accelerate`
+
+- 安装最新版本 `transformers`
+`pip install --upgrade transformers`
+
+#### 提示和最佳实践
+
+
+- **高级用法:** 请参考 [此 Google Colab notebook](https://colab.research.google.com/drive/1ge2F1QSK8Q7h0hn3YKuBCOAS0bK8E0wf) 以获取 4 位量化高级用法和所有可选选项。
+
+- **使用 `batch_size=1` 实现更快的推理:** 自 `bitsandbytes` 的 `0.40.0` 版本以来,设置 `batch_size=1`,您可以从快速推理中受益。请查看 [这些发布说明](https://github.com/TimDettmers/bitsandbytes/releases/tag/0.40.0) ,并确保使用大于 `0.40.0` 的版本以直接利用此功能。
+
+- **训练:** 根据 [QLoRA 论文](https://arxiv.org/abs/2305.14314),对于4位基模型训练(使用 LoRA 适配器),应使用 `bnb_4bit_quant_type='nf4'`。
+
+- **推理:** 对于推理,`bnb_4bit_quant_type` 对性能影响不大。但是为了与模型的权重保持一致,请确保使用相同的 `bnb_4bit_compute_dtype` 和 `torch_dtype` 参数。
+
+#### 加载 4 位量化的大模型
+
+在调用 `.from_pretrained` 方法时使用 `load_in_4bit=True`,可以将您的内存使用量减少到大约原来的 1/4。
+
+```python
+# pip install transformers accelerate bitsandbytes
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_id = "bigscience/bloom-1b7"
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id, device_map="auto", load_in_4bit=True)
+```
+
+
+
+需要注意的是,一旦模型以 4 位量化方式加载,就无法将量化后的权重推送到 Hub 上。此外,您不能训练 4 位量化权重,因为目前尚不支持此功能。但是,您可以使用 4 位量化模型来训练额外参数,这将在下一部分中介绍。
+
+
+
+### 加载 8 位量化的大模型
+
+您可以通过在调用 `.from_pretrained` 方法时使用 `load_in_8bit=True` 参数,将内存需求大致减半来加载模型
+
+
+```python
+# pip install transformers accelerate bitsandbytes
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+model_id = "bigscience/bloom-1b7"
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+```
+
+然后,像通常使用 `PreTrainedModel` 一样使用您的模型。
+
+您可以使用 `get_memory_footprint` 方法检查模型的内存占用。
+
+
+```python
+print(model.get_memory_footprint())
+```
+
+通过这种集成,我们能够在较小的设备上加载大模型并运行它们而没有任何问题。
+
+
+
+需要注意的是,一旦模型以 8 位量化方式加载,除了使用最新的 `transformers` 和 `bitsandbytes` 之外,目前尚无法将量化后的权重推送到 Hub 上。此外,您不能训练 8 位量化权重,因为目前尚不支持此功能。但是,您可以使用 8 位量化模型来训练额外参数,这将在下一部分中介绍。
+
+注意,`device_map` 是可选的,但设置 `device_map = 'auto'` 更适合用于推理,因为它将更有效地调度可用资源上的模型。
+
+
+
+
+#### 高级用例
+
+在这里,我们将介绍使用 FP4 量化的一些高级用例。
+
+##### 更改计算数据类型
+
+计算数据类型用于改变在进行计算时使用的数据类型。例如,hidden states可以是 `float32`,但为了加速,计算时可以被设置为 `bf16`。默认情况下,计算数据类型被设置为 `float32`。
+
+
+```python
+import torch
+from transformers import BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_4bit=True, bnb_4bit_compute_dtype=torch.bfloat16)
+```
+
+#### 使用 NF4(普通浮点数 4)数据类型
+
+您还可以使用 NF4 数据类型,这是一种针对使用正态分布初始化的权重而适应的新型 4 位数据类型。要运行:
+
+```python
+from transformers import BitsAndBytesConfig
+
+nf4_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_quant_type="nf4",
+)
+
+model_nf4 = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=nf4_config)
+```
+
+#### 使用嵌套量化进行更高效的内存推理
+
+我们还建议用户使用嵌套量化技术。从我们的经验观察来看,这种方法在不增加额外性能的情况下节省更多内存。这使得 llama-13b 模型能够在具有 1024 个序列长度、1 个批次大小和 4 个梯度累积步骤的 NVIDIA-T4 16GB 上进行 fine-tuning。
+
+```python
+from transformers import BitsAndBytesConfig
+
+double_quant_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_use_double_quant=True,
+)
+
+model_double_quant = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=double_quant_config)
+```
+
+### 将量化模型推送到🤗 Hub
+
+您可以使用 `push_to_hub` 方法将量化模型推送到 Hub 上。这将首先推送量化配置文件,然后推送量化模型权重。
+请确保使用 `bitsandbytes>0.37.2`(在撰写本文时,我们使用的是 `bitsandbytes==0.38.0.post1`)才能使用此功能。
+
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+model = AutoModelForCausalLM.from_pretrained("bigscience/bloom-560m", quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+tokenizer = AutoTokenizer.from_pretrained("bigscience/bloom-560m")
+
+model.push_to_hub("bloom-560m-8bit")
+```
+
+
+
+对大模型,强烈鼓励将 8 位量化模型推送到 Hub 上,以便让社区能够从内存占用减少和加载中受益,例如在 Google Colab 上加载大模型。
+
+
+
+### 从🤗 Hub加载量化模型
+
+您可以使用 `from_pretrained` 方法从 Hub 加载量化模型。请确保推送的权重是量化的,检查模型配置对象中是否存在 `quantization_config` 属性。
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained("{your_username}/bloom-560m-8bit", device_map="auto")
+```
+
+请注意,在这种情况下,您不需要指定 `load_in_8bit=True` 参数,但需要确保 `bitsandbytes` 和 `accelerate` 已安装。
+情注意,`device_map` 是可选的,但设置 `device_map = 'auto'` 更适合用于推理,因为它将更有效地调度可用资源上的模型。
+
+### 高级用例
+
+本节面向希望探索除了加载和运行 8 位模型之外还能做什么的进阶用户。
+
+#### 在 `cpu` 和 `gpu` 之间卸载
+
+此高级用例之一是能够加载模型并将权重分派到 `CPU` 和 `GPU` 之间。请注意,将在 CPU 上分派的权重 **不会** 转换为 8 位,因此会保留为 `float32`。此功能适用于想要适应非常大的模型并将模型分派到 GPU 和 CPU 之间的用户。
+
+首先,从 `transformers` 中加载一个 [`BitsAndBytesConfig`],并将属性 `llm_int8_enable_fp32_cpu_offload` 设置为 `True`:
+
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(llm_int8_enable_fp32_cpu_offload=True)
+```
+
+假设您想加载 `bigscience/bloom-1b7` 模型,您的 GPU显存仅足够容纳除了`lm_head`外的整个模型。因此,您可以按照以下方式编写自定义的 device_map:
+
+```python
+device_map = {
+ "transformer.word_embeddings": 0,
+ "transformer.word_embeddings_layernorm": 0,
+ "lm_head": "cpu",
+ "transformer.h": 0,
+ "transformer.ln_f": 0,
+}
+```
+
+然后如下加载模型:
+
+```python
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ "bigscience/bloom-1b7",
+ device_map=device_map,
+ quantization_config=quantization_config,
+)
+```
+
+这就是全部内容!享受您的模型吧!
+
+#### 使用`llm_int8_threshold`
+
+您可以使用 `llm_int8_threshold` 参数来更改异常值的阈值。“异常值”是一个大于特定阈值的`hidden state`值。
+这对应于`LLM.int8()`论文中描述的异常检测的异常阈值。任何高于此阈值的`hidden state`值都将被视为异常值,对这些值的操作将在 fp16 中完成。值通常是正态分布的,也就是说,大多数值在 [-3.5, 3.5] 范围内,但有一些额外的系统异常值,对于大模型来说,它们的分布非常不同。这些异常值通常在区间 [-60, -6] 或 [6, 60] 内。Int8 量化对于幅度为 ~5 的值效果很好,但超出这个范围,性能就会明显下降。一个好的默认阈值是 6,但对于更不稳定的模型(小模型、微调)可能需要更低的阈值。
+这个参数会影响模型的推理速度。我们建议尝试这个参数,以找到最适合您的用例的参数。
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+model_id = "bigscience/bloom-1b7"
+
+quantization_config = BitsAndBytesConfig(
+ llm_int8_threshold=10,
+)
+
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ model_id,
+ device_map=device_map,
+ quantization_config=quantization_config,
+)
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+```
+
+#### 跳过某些模块的转换
+
+一些模型有几个需要保持未转换状态以确保稳定性的模块。例如,Jukebox 模型有几个 `lm_head` 模块需要跳过。使用 `llm_int8_skip_modules` 参数进行相应操作。
+
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+model_id = "bigscience/bloom-1b7"
+
+quantization_config = BitsAndBytesConfig(
+ llm_int8_skip_modules=["lm_head"],
+)
+
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ model_id,
+ device_map=device_map,
+ quantization_config=quantization_config,
+)
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+```
+
+#### 微调已加载为8位精度的模型
+
+借助Hugging Face生态系统中适配器(adapters)的官方支持,您可以在8位精度下微调模型。这使得可以在单个Google Colab中微调大模型,例如`flan-t5-large`或`facebook/opt-6.7b`。请查看[`peft`](https://github.com/huggingface/peft)库了解更多详情。
+
+注意,加载模型进行训练时无需传递`device_map`。它将自动将您的模型加载到GPU上。如果需要,您可以将设备映射为特定设备(例如`cuda:0`、`0`、`torch.device('cuda:0')`)。请注意,`device_map=auto`仅应用于推理。
+
+
+### BitsAndBytesConfig
+
+[[autodoc]] BitsAndBytesConfig
+
+
+## 使用 🤗 `optimum` 进行量化
+
+请查看[Optimum 文档](https://huggingface.co/docs/optimum/index)以了解更多关于`optimum`支持的量化方法,并查看这些方法是否适用于您的用例。
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/text_generation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/text_generation.md
new file mode 100644
index 0000000000000000000000000000000000000000..22e31b63c14e6b97a61a2ef307d045938580b8da
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/text_generation.md
@@ -0,0 +1,51 @@
+
+
+# Generation
+
+每个框架都在它们各自的 `GenerationMixin` 类中实现了文本生成的 `generate` 方法:
+
+- PyTorch [`~generation.GenerationMixin.generate`] 在 [`~generation.GenerationMixin`] 中实现。
+- TensorFlow [`~generation.TFGenerationMixin.generate`] 在 [`~generation.TFGenerationMixin`] 中实现。
+- Flax/JAX [`~generation.FlaxGenerationMixin.generate`] 在 [`~generation.FlaxGenerationMixin`] 中实现。
+
+无论您选择哪个框架,都可以使用 [`~generation.GenerationConfig`] 类实例对 generate 方法进行参数化。有关生成方法的控制参数的完整列表,请参阅此类。
+
+要了解如何检查模型的生成配置、默认值是什么、如何临时更改参数以及如何创建和保存自定义生成配置,请参阅 [文本生成策略指南](../generation_strategies)。该指南还解释了如何使用相关功能,如token流。
+
+## GenerationConfig
+
+[[autodoc]] generation.GenerationConfig
+ - from_pretrained
+ - from_model_config
+ - save_pretrained
+
+## GenerationMixin
+
+[[autodoc]] generation.GenerationMixin
+ - generate
+ - compute_transition_scores
+
+## TFGenerationMixin
+
+[[autodoc]] generation.TFGenerationMixin
+ - generate
+ - compute_transition_scores
+
+## FlaxGenerationMixin
+
+[[autodoc]] generation.FlaxGenerationMixin
+ - generate
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/tokenizer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/tokenizer.md
new file mode 100644
index 0000000000000000000000000000000000000000..f89fc20b53d1d982fee32477e2c227a1066e772e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/tokenizer.md
@@ -0,0 +1,65 @@
+
+
+# Tokenizer
+
+tokenizer负责准备输入以供模型使用。该库包含所有模型的tokenizer。大多数tokenizer都有两种版本:一个是完全的 Python 实现,另一个是基于 Rust 库 [🤗 Tokenizers](https://github.com/huggingface/tokenizers) 的“Fast”实现。"Fast" 实现允许:
+
+1. 在批量分词时显著提速
+2. 在原始字符串(字符和单词)和token空间之间进行映射的其他方法(例如,获取包含给定字符的token的索引或与给定token对应的字符范围)。
+
+基类 [PreTrainedTokenizer] 和 [PreTrained TokenizerFast] 实现了在模型输入中编码字符串输入的常用方法(见下文),并从本地文件或目录或从库提供的预训练的 tokenizer(从 HuggingFace 的 AWS S3 存储库下载)实例化/保存 python 和“Fast” tokenizer。它们都依赖于包含常用方法的 [`~tokenization_utils_base.PreTrainedTokenizerBase`]和[`~tokenization_utils_base.SpecialTokensMixin`]。
+
+因此,[`PreTrainedTokenizer`] 和 [`PreTrainedTokenizerFast`] 实现了使用所有tokenizers的主要方法:
+
+- 分词(将字符串拆分为子词标记字符串),将tokens字符串转换为id并转换回来,以及编码/解码(即标记化并转换为整数)。
+- 以独立于底层结构(BPE、SentencePiece……)的方式向词汇表中添加新tokens。
+- 管理特殊tokens(如mask、句首等):添加它们,将它们分配给tokenizer中的属性以便于访问,并确保它们在标记过程中不会被分割。
+
+[`BatchEncoding`] 包含 [`~tokenization_utils_base.PreTrainedTokenizerBase`] 的编码方法(`__call__`、`encode_plus` 和 `batch_encode_plus`)的输出,并且是从 Python 字典派生的。当tokenizer是纯 Python tokenizer时,此类的行为就像标准的 Python 字典一样,并保存这些方法计算的各种模型输入(`input_ids`、`attention_mask` 等)。当分词器是“Fast”分词器时(即由 HuggingFace 的 [tokenizers 库](https://github.com/huggingface/tokenizers) 支持),此类还提供了几种高级对齐方法,可用于在原始字符串(字符和单词)与token空间之间进行映射(例如,获取包含给定字符的token的索引或与给定token对应的字符范围)。
+
+
+## PreTrainedTokenizer
+
+[[autodoc]] PreTrainedTokenizer
+ - __call__
+ - add_tokens
+ - add_special_tokens
+ - apply_chat_template
+ - batch_decode
+ - decode
+ - encode
+ - push_to_hub
+ - all
+
+## PreTrainedTokenizerFast
+
+[`PreTrainedTokenizerFast`] 依赖于 [tokenizers](https://huggingface.co/docs/tokenizers) 库。可以非常简单地将从 🤗 tokenizers 库获取的tokenizers加载到 🤗 transformers 中。查看 [使用 🤗 tokenizers 的分词器](../fast_tokenizers) 页面以了解如何执行此操作。
+
+[[autodoc]] PreTrainedTokenizerFast
+ - __call__
+ - add_tokens
+ - add_special_tokens
+ - apply_chat_template
+ - batch_decode
+ - decode
+ - encode
+ - push_to_hub
+ - all
+
+## BatchEncoding
+
+[[autodoc]] BatchEncoding
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/trainer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/trainer.md
new file mode 100644
index 0000000000000000000000000000000000000000..cb0262140cb22d564657ebc3df6b5e571270d0c6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/main_classes/trainer.md
@@ -0,0 +1,665 @@
+
+
+# Trainer
+
+[`Trainer`] 类提供了一个 PyTorch 的 API,用于处理大多数标准用例的全功能训练。它在大多数[示例脚本](https://github.com/huggingface/transformers/tree/main/examples)中被使用。
+
+
+
+如果你想要使用自回归技术在文本数据集上微调像 Llama-2 或 Mistral 这样的语言模型,考虑使用 [`trl`](https://github.com/huggingface/trl) 的 [`~trl.SFTTrainer`]。[`~trl.SFTTrainer`] 封装了 [`Trainer`],专门针对这个特定任务进行了优化,并支持序列打包、LoRA、量化和 DeepSpeed,以有效扩展到任何模型大小。另一方面,[`Trainer`] 是一个更通用的选项,适用于更广泛的任务。
+
+
+
+在实例化你的 [`Trainer`] 之前,创建一个 [`TrainingArguments`],以便在训练期间访问所有定制点。
+
+这个 API 支持在多个 GPU/TPU 上进行分布式训练,支持 [NVIDIA Apex](https://github.com/NVIDIA/apex) 的混合精度和 PyTorch 的原生 AMP。
+
+[`Trainer`] 包含基本的训练循环,支持上述功能。如果需要自定义训练,你可以继承 `Trainer` 并覆盖以下方法:
+
+- **get_train_dataloader** -- 创建训练 DataLoader。
+- **get_eval_dataloader** -- 创建评估 DataLoader。
+- **get_test_dataloader** -- 创建测试 DataLoader。
+- **log** -- 记录观察训练的各种对象的信息。
+- **create_optimizer_and_scheduler** -- 如果它们没有在初始化时传递,请设置优化器和学习率调度器。请注意,你还可以单独继承或覆盖 `create_optimizer` 和 `create_scheduler` 方法。
+- **create_optimizer** -- 如果在初始化时没有传递,则设置优化器。
+- **create_scheduler** -- 如果在初始化时没有传递,则设置学习率调度器。
+- **compute_loss** - 计算单批训练输入的损失。
+- **training_step** -- 执行一步训练。
+- **prediction_step** -- 执行一步评估/测试。
+- **evaluate** -- 运行评估循环并返回指标。
+- **predict** -- 返回在测试集上的预测(如果有标签,则包括指标)。
+
+
+
+[`Trainer`] 类被优化用于 🤗 Transformers 模型,并在你在其他模型上使用时可能会有一些令人惊讶的结果。当在你自己的模型上使用时,请确保:
+
+- 你的模型始终返回元组或 [`~utils.ModelOutput`] 的子类。
+- 如果提供了 `labels` 参数,你的模型可以计算损失,并且损失作为元组的第一个元素返回(如果你的模型返回元组)。
+- 你的模型可以接受多个标签参数(在 [`TrainingArguments`] 中使用 `label_names` 将它们的名称指示给 [`Trainer`]),但它们中没有一个应该被命名为 `"label"`。
+
+
+
+以下是如何自定义 [`Trainer`] 以使用加权损失的示例(在训练集不平衡时很有用):
+
+```python
+from torch import nn
+from transformers import Trainer
+
+
+class CustomTrainer(Trainer):
+ def compute_loss(self, model, inputs, return_outputs=False):
+ labels = inputs.pop("labels")
+ # forward pass
+ outputs = model(**inputs)
+ logits = outputs.get("logits")
+ # compute custom loss (suppose one has 3 labels with different weights)
+ loss_fct = nn.CrossEntropyLoss(weight=torch.tensor([1.0, 2.0, 3.0], device=model.device))
+ loss = loss_fct(logits.view(-1, self.model.config.num_labels), labels.view(-1))
+ return (loss, outputs) if return_outputs else loss
+```
+
+在 PyTorch [`Trainer`] 中自定义训练循环行为的另一种方法是使用 [callbacks](callback),这些回调可以检查训练循环状态(用于进度报告、在 TensorBoard 或其他 ML 平台上记录日志等)并做出决策(比如提前停止)。
+
+
+## Trainer
+
+[[autodoc]] Trainer - all
+
+## Seq2SeqTrainer
+
+[[autodoc]] Seq2SeqTrainer - evaluate - predict
+
+## TrainingArguments
+
+[[autodoc]] TrainingArguments - all
+
+## Seq2SeqTrainingArguments
+
+[[autodoc]] Seq2SeqTrainingArguments - all
+
+## Checkpoints
+
+默认情况下,[`Trainer`] 会将所有checkpoints保存在你使用的 [`TrainingArguments`] 中设置的 `output_dir` 中。这些checkpoints将位于名为 `checkpoint-xxx` 的子文件夹中,xxx 是训练的步骤。
+
+从checkpoints恢复训练可以通过调用 [`Trainer.train`] 时使用以下任一方式进行:
+
+- `resume_from_checkpoint=True`,这将从最新的checkpoint恢复训练。
+- `resume_from_checkpoint=checkpoint_dir`,这将从指定目录中的特定checkpoint恢复训练。
+
+此外,当使用 `push_to_hub=True` 时,你可以轻松将checkpoints保存在 Model Hub 中。默认情况下,保存在训练中间过程的checkpoints中的所有模型都保存在不同的提交中,但不包括优化器状态。你可以根据需要调整 [`TrainingArguments`] 的 `hub-strategy` 值:
+
+- `"checkpoint"`: 最新的checkpoint也被推送到一个名为 last-checkpoint 的子文件夹中,让你可以通过 `trainer.train(resume_from_checkpoint="output_dir/last-checkpoint")` 轻松恢复训练。
+- `"all_checkpoints"`: 所有checkpoints都像它们出现在输出文件夹中一样被推送(因此你将在最终存储库中的每个文件夹中获得一个checkpoint文件夹)。
+
+## Logging
+
+默认情况下,[`Trainer`] 将对主进程使用 `logging.INFO`,对副本(如果有的话)使用 `logging.WARNING`。
+
+可以通过 [`TrainingArguments`] 的参数覆盖这些默认设置,使用其中的 5 个 `logging` 级别:
+
+- `log_level` - 用于主进程
+- `log_level_replica` - 用于副本
+
+此外,如果 [`TrainingArguments`] 的 `log_on_each_node` 设置为 `False`,则只有主节点将使用其主进程的日志级别设置,所有其他节点将使用副本的日志级别设置。
+
+请注意,[`Trainer`] 将在其 [`Trainer.__init__`] 中分别为每个节点设置 `transformers` 的日志级别。因此,如果在创建 [`Trainer`] 对象之前要调用其他 `transformers` 功能,可能需要更早地设置这一点(请参见下面的示例)。
+
+以下是如何在应用程序中使用的示例:
+
+```python
+[...]
+logger = logging.getLogger(__name__)
+
+# Setup logging
+logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+)
+
+# set the main code and the modules it uses to the same log-level according to the node
+log_level = training_args.get_process_log_level()
+logger.setLevel(log_level)
+datasets.utils.logging.set_verbosity(log_level)
+transformers.utils.logging.set_verbosity(log_level)
+
+trainer = Trainer(...)
+```
+
+然后,如果你只想在主节点上看到警告,并且所有其他节点不打印任何可能重复的警告,可以这样运行:
+
+```bash
+my_app.py ... --log_level warning --log_level_replica error
+```
+
+在多节点环境中,如果你也不希望每个节点的主进程的日志重复输出,你需要将上面的代码更改为:
+
+```bash
+my_app.py ... --log_level warning --log_level_replica error --log_on_each_node 0
+```
+
+然后,只有第一个节点的主进程将以 "warning" 级别记录日志,主节点上的所有其他进程和其他节点上的所有进程将以 "error" 级别记录日志。
+
+如果你希望应用程序尽可能”安静“,可以执行以下操作:
+
+
+```bash
+my_app.py ... --log_level error --log_level_replica error --log_on_each_node 0
+```
+
+(如果在多节点环境,添加 `--log_on_each_node 0`)
+
+
+## 随机性
+
+当从 [`Trainer`] 生成的checkpoint恢复训练时,程序会尽一切努力将 _python_、_numpy_ 和 _pytorch_ 的 RNG(随机数生成器)状态恢复为保存检查点时的状态,这样可以使“停止和恢复”式训练尽可能接近“非停止式”训练。
+
+然而,由于各种默认的非确定性 PyTorch 设置,这可能无法完全实现。如果你想要完全确定性,请参阅[控制随机源](https://pytorch.org/docs/stable/notes/randomness)。正如文档中所解释的那样,使事物变得确定的一些设置(例如 `torch.backends.cudnn.deterministic`)可能会减慢速度,因此不能默认执行,但如果需要,你可以自行启用这些设置。
+
+
+## 特定GPU选择
+
+让我们讨论一下如何告诉你的程序应该使用哪些 GPU 以及使用的顺序。
+
+当使用 [`DistributedDataParallel`](https://pytorch.org/docs/stable/generated/torch.nn.parallel.DistributedDataParallel.html) 且仅使用部分 GPU 时,你只需指定要使用的 GPU 数量。例如,如果你有 4 个 GPU,但只想使用前 2 个,可以执行以下操作:
+
+
+```bash
+python -m torch.distributed.launch --nproc_per_node=2 trainer-program.py ...
+```
+
+如果你安装了 [`accelerate`](https://github.com/huggingface/accelerate) 或 [`deepspeed`](https://github.com/microsoft/DeepSpeed),你还可以通过以下任一方法实现相同的效果:
+
+
+```bash
+accelerate launch --num_processes 2 trainer-program.py ...
+```
+
+```bash
+deepspeed --num_gpus 2 trainer-program.py ...
+```
+
+你不需要使用 Accelerate 或 [Deepspeed 集成](Deepspeed) 功能来使用这些启动器。
+
+到目前为止,你已经能够告诉程序要使用多少个 GPU。现在让我们讨论如何选择特定的 GPU 并控制它们的顺序。
+
+以下环境变量可帮助你控制使用哪些 GPU 以及它们的顺序。
+
+
+**`CUDA_VISIBLE_DEVICES`**
+
+如果你有多个 GPU,想要仅使用其中的一个或几个 GPU,请将环境变量 `CUDA_VISIBLE_DEVICES` 设置为要使用的 GPU 列表。
+
+例如,假设你有 4 个 GPU:0、1、2 和 3。要仅在物理 GPU 0 和 2 上运行,你可以执行以下操作:
+
+
+```bash
+CUDA_VISIBLE_DEVICES=0,2 python -m torch.distributed.launch trainer-program.py ...
+```
+
+现在,PyTorch 将只看到 2 个 GPU,其中你的物理 GPU 0 和 2 分别映射到 `cuda:0` 和 `cuda:1`。
+
+你甚至可以改变它们的顺序:
+
+
+```bash
+CUDA_VISIBLE_DEVICES=2,0 python -m torch.distributed.launch trainer-program.py ...
+```
+
+这里,你的物理 GPU 0 和 2 分别映射到 `cuda:1` 和 `cuda:0`。
+
+上面的例子都是针对 `DistributedDataParallel` 使用模式的,但同样的方法也适用于 [`DataParallel`](https://pytorch.org/docs/stable/generated/torch.nn.DataParallel.html):
+
+
+```bash
+CUDA_VISIBLE_DEVICES=2,0 python trainer-program.py ...
+```
+
+为了模拟没有 GPU 的环境,只需将此环境变量设置为空值,如下所示:
+
+```bash
+CUDA_VISIBLE_DEVICES= python trainer-program.py ...
+```
+
+与任何环境变量一样,你当然可以将其export到环境变量而不是将其添加到命令行,如下所示:
+
+
+```bash
+export CUDA_VISIBLE_DEVICES=0,2
+python -m torch.distributed.launch trainer-program.py ...
+```
+
+这种方法可能会令人困惑,因为你可能会忘记之前设置了环境变量,进而不明白为什么会使用错误的 GPU。因此,在同一命令行中仅为特定运行设置环境变量是一种常见做法,正如本节大多数示例所示。
+
+
+**`CUDA_DEVICE_ORDER`**
+
+还有一个额外的环境变量 `CUDA_DEVICE_ORDER`,用于控制物理设备的排序方式。有两个选择:
+
+1. 按 PCIe 总线 ID 排序(与 nvidia-smi 的顺序相匹配)- 这是默认选项。
+
+
+```bash
+export CUDA_DEVICE_ORDER=PCI_BUS_ID
+```
+
+2. 按 GPU 计算能力排序。
+
+```bash
+export CUDA_DEVICE_ORDER=FASTEST_FIRST
+```
+
+大多数情况下,你不需要关心这个环境变量,但如果你的设置不均匀,那么这将非常有用,例如,您的旧 GPU 和新 GPU 物理上安装在一起,但让速度较慢的旧卡排在运行的第一位。解决这个问题的一种方法是交换卡的位置。但如果不能交换卡(例如,如果设备的散热受到影响),那么设置 `CUDA_DEVICE_ORDER=FASTEST_FIRST` 将始终将较新、更快的卡放在第一位。但这可能会有点混乱,因为 `nvidia-smi` 仍然会按照 PCIe 顺序报告它们。
+
+交换卡的顺序的另一种方法是使用:
+
+
+```bash
+export CUDA_VISIBLE_DEVICES=1,0
+```
+
+在此示例中,我们只使用了 2 个 GPU,但是当然,对于计算机上有的任何数量的 GPU,都适用相同的方法。
+
+此外,如果你设置了这个环境变量,最好将其设置在 `~/.bashrc` 文件或其他启动配置文件中,然后就可以忘记它了。
+
+
+## Trainer集成
+
+[`Trainer`] 已经被扩展,以支持可能显著提高训练时间并适应更大模型的库。
+
+目前,它支持第三方解决方案 [DeepSpeed](https://github.com/microsoft/DeepSpeed) 和 [PyTorch FSDP](https://pytorch.org/docs/stable/fsdp.html),它们实现了论文 [ZeRO: Memory Optimizations Toward Training Trillion Parameter Models, by Samyam Rajbhandari, Jeff Rasley, Olatunji Ruwase, Yuxiong He](https://arxiv.org/abs/1910.02054) 的部分内容。
+
+截至撰写本文,此提供的支持是新的且实验性的。尽管我们欢迎围绕 DeepSpeed 和 PyTorch FSDP 的issues,但我们不再支持 FairScale 集成,因为它已经集成到了 PyTorch 主线(参见 [PyTorch FSDP 集成](#pytorch-fully-sharded-data-parallel))。
+
+
+` 传递。它可以是FSDP json配置文件的位置(例如,`fsdp_config.json`)或已加载的json文件作为 `dict`。
+ - 如果启用了自动包装,您可以使用基于transformer的自动包装策略或基于大小的自动包装策略。
+ - 对于基于transformer的自动包装策略,建议在配置文件中指定 `fsdp_transformer_layer_cls_to_wrap`。如果未指定,则默认值为 `model._no_split_modules`(如果可用)。这将指定要包装的transformer层类名(区分大小写),例如 [`BertLayer`]、[`GPTJBlock`]、[`T5Block`] 等。这很重要,因为共享权重的子模块(例如,embedding层)不应最终出现在不同的FSDP包装单元中。使用此策略,每个包装的块将包含多头注意力和后面的几个MLP层。剩余的层,包括共享的embedding层,都将被方便地包装在同一个最外层的FSDP单元中。因此,对于基于transformer的模型,请使用这个方法。
+ - 对于基于大小的自动包装策略,请在配置文件中添加 `fsdp_min_num_params`。它指定了FSDP进行自动包装的最小参数数量。
+ - 可以在配置文件中指定 `fsdp_backward_prefetch`。它控制何时预取下一组参数。`backward_pre` 和 `backward_pos` 是可用的选项。有关更多信息,请参阅 `torch.distributed.fsdp.fully_sharded_data_parallel.BackwardPrefetch`
+ - 可以在配置文件中指定 `fsdp_forward_prefetch`。它控制何时预取下一组参数。如果是`"True"`,在执行前向传递时,FSDP明确地预取下一次即将发生的全局聚集。
+ - 可以在配置文件中指定 `limit_all_gathers`。如果是`"True"`,FSDP明确地同步CPU线程,以防止太多的进行中的全局聚集。
+ - 可以在配置文件中指定 `activation_checkpointing`。如果是`"True"`,FSDP activation checkpoint是一种通过清除某些层的激活值并在反向传递期间重新计算它们来减少内存使用的技术。实际上,这以更多的计算时间为代价减少了内存使用。
+
+
+**需要注意几个注意事项**
+- 它与 `generate` 不兼容,因此与所有seq2seq/clm脚本(翻译/摘要/clm等)中的 `--predict_with_generate` 不兼容。请参阅issue[#21667](https://github.com/huggingface/transformers/issues/21667)。
+
+
+### PyTorch/XLA 完全分片数据并行
+
+对于所有TPU用户,有个好消息!PyTorch/XLA现在支持FSDP。所有最新的完全分片数据并行(FSDP)训练都受支持。有关更多信息,请参阅[在云端TPU上使用FSDP扩展PyTorch模型](https://pytorch.org/blog/scaling-pytorch-models-on-cloud-tpus-with-fsdp/)和[PyTorch/XLA FSDP的实现](https://github.com/pytorch/xla/tree/master/torch_xla/distributed/fsdp)。使用它只需通过配置启用。
+
+**需要的 PyTorch/XLA 版本以支持 FSDP**:>=2.0
+
+**用法**:
+
+传递 `--fsdp "full shard"`,同时对 `--fsdp_config ` 进行以下更改:
+- `xla` 应设置为 `True` 以启用 PyTorch/XLA FSDP。
+- `xla_fsdp_settings` 的值是一个字典,存储 XLA FSDP 封装参数。完整的选项列表,请参见[此处](https://github.com/pytorch/xla/blob/master/torch_xla/distributed/fsdp/xla_fully_sharded_data_parallel.py)。
+- `xla_fsdp_grad_ckpt`。当 `True` 时,在每个嵌套的 XLA FSDP 封装层上使用梯度checkpoint。该设置只能在将 xla 标志设置为 true,并通过 `fsdp_min_num_params` 或 `fsdp_transformer_layer_cls_to_wrap` 指定自动包装策略时使用。
+- 您可以使用基于transformer的自动包装策略或基于大小的自动包装策略。
+ - 对于基于transformer的自动包装策略,建议在配置文件中指定 `fsdp_transformer_layer_cls_to_wrap`。如果未指定,默认值为 `model._no_split_modules`(如果可用)。这指定了要包装的transformer层类名列表(区分大小写),例如 [`BertLayer`]、[`GPTJBlock`]、[`T5Block`] 等。这很重要,因为共享权重的子模块(例如,embedding层)不应最终出现在不同的FSDP包装单元中。使用此策略,每个包装的块将包含多头注意力和后面的几个MLP层。剩余的层,包括共享的embedding层,都将被方便地包装在同一个最外层的FSDP单元中。因此,对于基于transformer的模型,请使用这个方法。
+ - 对于基于大小的自动包装策略,请在配置文件中添加 `fsdp_min_num_params`。它指定了自动包装的 FSDP 的最小参数数量。
+
+
+### 在 Mac 上使用 Trainer 进行加速的 PyTorch 训练
+
+随着 PyTorch v1.12 版本的发布,开发人员和研究人员可以利用 Apple Silicon GPU 进行显著更快的模型训练。这使得可以在 Mac 上本地执行原型设计和微调等机器学习工作流程。Apple 的 Metal Performance Shaders(MPS)作为 PyTorch 的后端实现了这一点,并且可以通过新的 `"mps"` 设备来使用。
+这将在 MPS 图形框架上映射计算图和神经图元,并使用 MPS 提供的优化内核。更多信息,请参阅官方文档 [Introducing Accelerated PyTorch Training on Mac](https://pytorch.org/blog/introducing-accelerated-pytorch-training-on-mac/) 和 [MPS BACKEND](https://pytorch.org/docs/stable/notes/mps.html)。
+
+
+
+
+我们强烈建议在你的 MacOS 机器上安装 PyTorch >= 1.13(在撰写本文时为最新版本)。对于基于 transformer 的模型, 它提供与模型正确性和性能改进相关的重大修复。有关更多详细信息,请参阅[pytorch/pytorch#82707](https://github.com/pytorch/pytorch/issues/82707)。
+
+
+
+**使用 Apple Silicon 芯片进行训练和推理的好处**
+
+1. 使用户能够在本地训练更大的网络或批量数据。
+2. 由于统一内存架构,减少数据检索延迟,并为 GPU 提供对完整内存存储的直接访问。从而提高端到端性能。
+3. 降低与基于云的开发或需要额外本地 GPU 的成本。
+
+**先决条件**:要安装带有 mps 支持的 torch,请按照这篇精彩的 Medium 文章操作 [GPU-Acceleration Comes to PyTorch on M1 Macs](https://medium.com/towards-data-science/gpu-acceleration-comes-to-pytorch-on-m1-macs-195c399efcc1)。
+
+**用法**:
+如果可用,`mps` 设备将默认使用,类似于使用 `cuda` 设备的方式。因此,用户无需采取任何操作。例如,您可以使用以下命令在 Apple Silicon GPU 上运行官方的 Glue 文本分类任务(从根文件夹运行):
+
+```bash
+export TASK_NAME=mrpc
+
+python examples/pytorch/text-classification/run_glue.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --task_name $TASK_NAME \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 32 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/ \
+ --overwrite_output_dir
+```
+
+**需要注意的一些注意事项**
+
+1. 一些 PyTorch 操作尚未在 mps 中实现,将引发错误。解决此问题的一种方法是设置环境变量 `PYTORCH_ENABLE_MPS_FALLBACK=1`,它将把这些操作回退到 CPU 进行。然而,它仍然会抛出 UserWarning 信息。
+2. 分布式设置 `gloo` 和 `nccl` 在 `mps` 设备上不起作用。这意味着当前只能使用 `mps` 设备类型的单个 GPU。
+
+最后,请记住,🤗 `Trainer` 仅集成了 MPS 后端,因此如果你在使用 MPS 后端时遇到任何问题或有疑问,请在 [PyTorch GitHub](https://github.com/pytorch/pytorch/issues) 上提交问题。
+
+
+## 通过 Accelerate Launcher 使用 Trainer
+
+Accelerate 现在支持 Trainer。用户可以期待以下内容:
+- 他们可以继续使用 Trainer 的迭代,如 FSDP、DeepSpeed 等,而无需做任何更改。
+- 现在可以在 Trainer 中使用 Accelerate Launcher(建议使用)。
+
+通过 Accelerate Launcher 使用 Trainer 的步骤:
+1. 确保已安装 🤗 Accelerate,无论如何,如果没有它,你无法使用 `Trainer`。如果没有,请执行 `pip install accelerate`。你可能还需要更新 Accelerate 的版本:`pip install accelerate --upgrade`。
+2. 运行 `accelerate config` 并填写问题。以下是一些加速配置的示例:
+
+ a. DDP 多节点多 GPU 配置:
+
+ ```yaml
+ compute_environment: LOCAL_MACHINE
+ distributed_type: MULTI_GPU
+ downcast_bf16: 'no'
+ gpu_ids: all
+ machine_rank: 0 #change rank as per the node
+ main_process_ip: 192.168.20.1
+ main_process_port: 9898
+ main_training_function: main
+ mixed_precision: fp16
+ num_machines: 2
+ num_processes: 8
+ rdzv_backend: static
+ same_network: true
+ tpu_env: []
+ tpu_use_cluster: false
+ tpu_use_sudo: false
+ use_cpu: false
+ ```
+
+ b. FSDP 配置:
+
+ ```yaml
+ compute_environment: LOCAL_MACHINE
+ distributed_type: FSDP
+ downcast_bf16: 'no'
+ fsdp_config:
+ fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
+ fsdp_backward_prefetch_policy: BACKWARD_PRE
+ fsdp_forward_prefetch: true
+ fsdp_offload_params: false
+ fsdp_sharding_strategy: 1
+ fsdp_state_dict_type: FULL_STATE_DICT
+ fsdp_sync_module_states: true
+ fsdp_transformer_layer_cls_to_wrap: BertLayer
+ fsdp_use_orig_params: true
+ machine_rank: 0
+ main_training_function: main
+ mixed_precision: bf16
+ num_machines: 1
+ num_processes: 2
+ rdzv_backend: static
+ same_network: true
+ tpu_env: []
+ tpu_use_cluster: false
+ tpu_use_sudo: false
+ use_cpu: false
+ ```
+
+ c. 指向文件的 DeepSpeed 配置:
+
+ ```yaml
+ compute_environment: LOCAL_MACHINE
+ deepspeed_config:
+ deepspeed_config_file: /home/user/configs/ds_zero3_config.json
+ zero3_init_flag: true
+ distributed_type: DEEPSPEED
+ downcast_bf16: 'no'
+ machine_rank: 0
+ main_training_function: main
+ num_machines: 1
+ num_processes: 4
+ rdzv_backend: static
+ same_network: true
+ tpu_env: []
+ tpu_use_cluster: false
+ tpu_use_sudo: false
+ use_cpu: false
+ ```
+
+ d. 使用 accelerate 插件的 DeepSpeed 配置:
+
+ ```yaml
+ compute_environment: LOCAL_MACHINE
+ deepspeed_config:
+ gradient_accumulation_steps: 1
+ gradient_clipping: 0.7
+ offload_optimizer_device: cpu
+ offload_param_device: cpu
+ zero3_init_flag: true
+ zero_stage: 2
+ distributed_type: DEEPSPEED
+ downcast_bf16: 'no'
+ machine_rank: 0
+ main_training_function: main
+ mixed_precision: bf16
+ num_machines: 1
+ num_processes: 4
+ rdzv_backend: static
+ same_network: true
+ tpu_env: []
+ tpu_use_cluster: false
+ tpu_use_sudo: false
+ use_cpu: false
+ ```
+
+3. 使用accelerate配置文件参数或启动器参数以外的参数运行Trainer脚本。以下是一个使用上述FSDP配置从accelerate启动器运行`run_glue.py`的示例。
+
+```bash
+cd transformers
+
+accelerate launch \
+./examples/pytorch/text-classification/run_glue.py \
+--model_name_or_path google-bert/bert-base-cased \
+--task_name $TASK_NAME \
+--do_train \
+--do_eval \
+--max_seq_length 128 \
+--per_device_train_batch_size 16 \
+--learning_rate 5e-5 \
+--num_train_epochs 3 \
+--output_dir /tmp/$TASK_NAME/ \
+--overwrite_output_dir
+```
+
+4. 你也可以直接使用`accelerate launch`的cmd参数。上面的示例将映射到:
+
+```bash
+cd transformers
+
+accelerate launch --num_processes=2 \
+--use_fsdp \
+--mixed_precision=bf16 \
+--fsdp_auto_wrap_policy=TRANSFORMER_BASED_WRAP \
+--fsdp_transformer_layer_cls_to_wrap="BertLayer" \
+--fsdp_sharding_strategy=1 \
+--fsdp_state_dict_type=FULL_STATE_DICT \
+./examples/pytorch/text-classification/run_glue.py
+--model_name_or_path google-bert/bert-base-cased \
+--task_name $TASK_NAME \
+--do_train \
+--do_eval \
+--max_seq_length 128 \
+--per_device_train_batch_size 16 \
+--learning_rate 5e-5 \
+--num_train_epochs 3 \
+--output_dir /tmp/$TASK_NAME/ \
+--overwrite_output_dir
+```
+
+有关更多信息,请参阅 🤗 Accelerate CLI 指南:[启动您的 🤗 Accelerate 脚本](https://huggingface.co/docs/accelerate/basic_tutorials/launch)。
+
+已移动的部分:
+
+[ DeepSpeed Installation Deployment with multiple GPUs Deployment with one GPU Deployment in Notebooks Configuration Passing Configuration Shared Configuration ZeRO ZeRO-2 Config ZeRO-3 Config NVMe Support ZeRO-2 vs ZeRO-3 Performance ZeRO-2 Example ZeRO-3 Example Optimizer Scheduler fp32 Precision Automatic Mixed Precision Batch Size Gradient Accumulation Gradient Clipping Getting The Model Weights Out
+
+
VIDEO
+
+
+
+要与社区共享模型,您需要在[huggingface.co](https://huggingface.co/join)上拥有一个帐户。您还可以加入现有的组织或创建一个新的组织。
+
+
+
+## 仓库功能
+
+Model Hub上的每个仓库都像是一个典型的GitHub仓库。我们的仓库提供版本控制、提交历史记录以及可视化差异的能力。
+
+Model Hub的内置版本控制基于git和[git-lfs](https://git-lfs.github.com/)。换句话说,您可以将一个模型视为一个仓库,从而实现更好的访问控制和可扩展性。版本控制允许使用*修订*方法来固定特定版本的模型,可以使用提交哈希值、标签或分支来标记。
+
+因此,您可以通过`revision`参数加载特定的模型版本:
+
+```py
+>>> model = AutoModel.from_pretrained(
+... "julien-c/EsperBERTo-small", revision="4c77982" # tag name, or branch name, or commit hash
+... )
+```
+
+文件也可以轻松地在仓库中编辑,您可以查看提交历史记录以及差异:
+
+
+## 设置
+
+在将模型共享到Hub之前,您需要拥有Hugging Face的凭证。如果您有访问终端的权限,请在安装🤗 Transformers的虚拟环境中运行以下命令。这将在您的Hugging Face缓存文件夹(默认为`~/.cache/`)中存储您的`access token`:
+
+
+```bash
+huggingface-cli login
+```
+
+如果您正在使用像Jupyter或Colaboratory这样的`notebook`,请确保您已安装了[`huggingface_hub`](https://huggingface.co/docs/hub/adding-a-library)库。该库允许您以编程方式与Hub进行交互。
+
+```bash
+pip install huggingface_hub
+```
+然后使用`notebook_login`登录到Hub,并按照[这里](https://huggingface.co/settings/token)的链接生成一个token进行登录:
+
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## 转换模型适用于所有框架
+
+为确保您的模型可以被使用不同框架的人使用,我们建议您将PyTorch和TensorFlow `checkpoints`都转换并上传。如果您跳过此步骤,用户仍然可以从其他框架加载您的模型,但速度会变慢,因为🤗 Transformers需要实时转换`checkpoints`。
+
+为另一个框架转换`checkpoints`很容易。确保您已安装PyTorch和TensorFlow(请参阅[此处](installation)的安装说明),然后在其他框架中找到适合您任务的特定模型。
+
+
+
+
+指定`from_tf=True`将checkpoint从TensorFlow转换为PyTorch。
+
+```py
+>>> pt_model = DistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_tf=True)
+>>> pt_model.save_pretrained("path/to/awesome-name-you-picked")
+```
+
+
+
+指定`from_pt=True`将checkpoint从PyTorch转换为TensorFlow。
+
+```py
+>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_pt=True)
+```
+
+然后,您可以使用新的checkpoint保存您的新TensorFlow模型:
+
+```py
+>>> tf_model.save_pretrained("path/to/awesome-name-you-picked")
+```
+
+
+
+如果模型在Flax中可用,您还可以将PyTorch checkpoint转换为Flax:
+
+```py
+>>> flax_model = FlaxDistilBertForSequenceClassification.from_pretrained(
+... "path/to/awesome-name-you-picked", from_pt=True
+... )
+```
+
+
+
+## 在训练过程中推送模型
+
+
+
+
+
+
+使用[`PushToHubCallback`]将模型分享到Hub。在[`PushToHubCallback`]函数中,添加以下内容:
+
+- 一个用于存储模型的输出目录。
+- 一个tokenizer。
+- `hub_model_id`,即您的Hub用户名和模型名称。
+
+
+```py
+>>> from transformers import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="./your_model_save_path", tokenizer=tokenizer, hub_model_id="your-username/my-awesome-model"
+... )
+```
+
+将回调函数添加到 [`fit`](https://keras.io/api/models/model_training_apis/)中,然后🤗 Transformers 会将训练好的模型推送到 Hub:
+
+```py
+>>> model.fit(tf_train_dataset, validation_data=tf_validation_dataset, epochs=3, callbacks=push_to_hub_callback)
+```
+
+
+
+## 使用`push_to_hub`功能
+
+您可以直接在您的模型上调用`push_to_hub`来将其上传到Hub。
+
+在`push_to_hub`中指定你的模型名称:
+
+```py
+>>> pt_model.push_to_hub("my-awesome-model")
+```
+
+这会在您的用户名下创建一个名为`my-awesome-model`的仓库。用户现在可以使用`from_pretrained`函数加载您的模型:
+
+```py
+>>> from transformers import AutoModel
+
+>>> model = AutoModel.from_pretrained("your_username/my-awesome-model")
+```
+
+如果您属于一个组织,并希望将您的模型推送到组织名称下,只需将其添加到`repo_id`中:
+
+```py
+>>> pt_model.push_to_hub("my-awesome-org/my-awesome-model")
+```
+
+`push_to_hub`函数还可以用于向模型仓库添加其他文件。例如,向模型仓库中添加一个`tokenizer`:
+
+```py
+>>> tokenizer.push_to_hub("my-awesome-model")
+```
+
+或者,您可能希望将您的微调后的PyTorch模型的TensorFlow版本添加进去:
+
+```py
+>>> tf_model.push_to_hub("my-awesome-model")
+```
+现在,当您导航到您的Hugging Face个人资料时,您应该看到您新创建的模型仓库。点击**文件**选项卡将显示您已上传到仓库的所有文件。
+
+有关如何创建和上传文件到仓库的更多详细信息,请参考Hub文档[这里](https://huggingface.co/docs/hub/how-to-upstream)。
+
+
+## 使用Web界面上传
+
+喜欢无代码方法的用户可以通过Hugging Face的Web界面上传模型。访问[huggingface.co/new](https://huggingface.co/new)创建一个新的仓库:
+
+
+
+从这里开始,添加一些关于您的模型的信息:
+
+- 选择仓库的**所有者**。这可以是您本人或者您所属的任何组织。
+- 为您的项目选择一个名称,该名称也将成为仓库的名称。
+- 选择您的模型是公开还是私有。
+- 指定您的模型的许可证使用情况。
+
+现在点击**文件**选项卡,然后点击**添加文件**按钮将一个新文件上传到你的仓库。接着拖放一个文件进行上传,并添加提交信息。
+
+
+
+## 添加模型卡片
+
+为了确保用户了解您的模型的能力、限制、潜在偏差和伦理考虑,请在仓库中添加一个模型卡片。模型卡片在`README.md`文件中定义。你可以通过以下方式添加模型卡片:
+
+* 手动创建并上传一个`README.md`文件。
+* 在你的模型仓库中点击**编辑模型卡片**按钮。
+
+可以参考DistilBert的[模型卡片](https://huggingface.co/distilbert/distilbert-base-uncased)来了解模型卡片应该包含的信息类型。有关您可以在`README.md`文件中控制的更多选项的细节,例如模型的碳足迹或小部件示例,请参考文档[这里](https://huggingface.co/docs/hub/models-cards)。
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/multilingual.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/multilingual.md
new file mode 100644
index 0000000000000000000000000000000000000000..9c27bd5f335ba023464a615ff535c74bf85e5b58
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/multilingual.md
@@ -0,0 +1,178 @@
+
+
+# 用于推理的多语言模型
+
+[[open-in-colab]]
+
+🤗 Transformers 中有多种多语言模型,它们的推理用法与单语言模型不同。但是,并非*所有*的多语言模型用法都不同。一些模型,例如 [google-bert/bert-base-multilingual-uncased](https://huggingface.co/google-bert/bert-base-multilingual-uncased) 就可以像单语言模型一样使用。本指南将向您展示如何使用不同用途的多语言模型进行推理。
+
+## XLM
+
+XLM 有十个不同的检查点,其中只有一个是单语言的。剩下的九个检查点可以归为两类:使用语言嵌入的检查点和不使用语言嵌入的检查点。
+
+### 带有语言嵌入的 XLM
+
+以下 XLM 模型使用语言嵌入来指定推理中使用的语言:
+
+- `FacebookAI/xlm-mlm-ende-1024` (掩码语言建模,英语-德语)
+- `FacebookAI/xlm-mlm-enfr-1024` (掩码语言建模,英语-法语)
+- `FacebookAI/xlm-mlm-enro-1024` (掩码语言建模,英语-罗马尼亚语)
+- `FacebookAI/xlm-mlm-xnli15-1024` (掩码语言建模,XNLI 数据集语言)
+- `FacebookAI/xlm-mlm-tlm-xnli15-1024` (掩码语言建模+翻译,XNLI 数据集语言)
+- `FacebookAI/xlm-clm-enfr-1024` (因果语言建模,英语-法语)
+- `FacebookAI/xlm-clm-ende-1024` (因果语言建模,英语-德语)
+
+语言嵌入被表示一个张量,其形状与传递给模型的 `input_ids` 相同。这些张量中的值取决于所使用的语言,并由分词器的 `lang2id` 和 `id2lang` 属性识别。
+
+在此示例中,加载 `FacebookAI/xlm-clm-enfr-1024` 检查点(因果语言建模,英语-法语):
+
+```py
+>>> import torch
+>>> from transformers import XLMTokenizer, XLMWithLMHeadModel
+
+>>> tokenizer = XLMTokenizer.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
+>>> model = XLMWithLMHeadModel.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
+```
+
+分词器的 `lang2id` 属性显示了该模型的语言及其对应的id:
+
+```py
+>>> print(tokenizer.lang2id)
+{'en': 0, 'fr': 1}
+```
+
+接下来,创建一个示例输入:
+
+```py
+>>> input_ids = torch.tensor([tokenizer.encode("Wikipedia was used to")]) # batch size 为 1
+```
+
+将语言 id 设置为 `"en"` 并用其定义语言嵌入。语言嵌入是一个用 `0` 填充的张量,这个张量应该与 `input_ids` 大小相同。
+
+```py
+>>> language_id = tokenizer.lang2id["en"] # 0
+>>> langs = torch.tensor([language_id] * input_ids.shape[1]) # torch.tensor([0, 0, 0, ..., 0])
+
+>>> # 我们将其 reshape 为 (batch_size, sequence_length) 大小
+>>> langs = langs.view(1, -1) # 现在的形状是 [1, sequence_length] (我们的 batch size 为 1)
+```
+
+现在,你可以将 `input_ids` 和语言嵌入传递给模型:
+
+```py
+>>> outputs = model(input_ids, langs=langs)
+```
+
+[run_generation.py](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-generation/run_generation.py) 脚本可以使用 `xlm-clm` 检查点生成带有语言嵌入的文本。
+
+### 不带语言嵌入的 XLM
+
+以下 XLM 模型在推理时不需要语言嵌入:
+
+- `FacebookAI/xlm-mlm-17-1280` (掩码语言建模,支持 17 种语言)
+- `FacebookAI/xlm-mlm-100-1280` (掩码语言建模,支持 100 种语言)
+
+与之前的 XLM 检查点不同,这些模型用于通用句子表示。
+
+## BERT
+
+以下 BERT 模型可用于多语言任务:
+
+- `google-bert/bert-base-multilingual-uncased` (掩码语言建模 + 下一句预测,支持 102 种语言)
+- `google-bert/bert-base-multilingual-cased` (掩码语言建模 + 下一句预测,支持 104 种语言)
+
+这些模型在推理时不需要语言嵌入。它们应该能够从上下文中识别语言并进行相应的推理。
+
+## XLM-RoBERTa
+
+以下 XLM-RoBERTa 模型可用于多语言任务:
+
+- `FacebookAI/xlm-roberta-base` (掩码语言建模,支持 100 种语言)
+- `FacebookAI/xlm-roberta-large` (掩码语言建模,支持 100 种语言)
+
+XLM-RoBERTa 使用 100 种语言的 2.5TB 新创建和清理的 CommonCrawl 数据进行了训练。与之前发布的 mBERT 或 XLM 等多语言模型相比,它在分类、序列标记和问答等下游任务上提供了更强大的优势。
+
+## M2M100
+
+以下 M2M100 模型可用于多语言翻译:
+
+- `facebook/m2m100_418M` (翻译)
+- `facebook/m2m100_1.2B` (翻译)
+
+在此示例中,加载 `facebook/m2m100_418M` 检查点以将中文翻译为英文。你可以在分词器中设置源语言:
+
+```py
+>>> from transformers import M2M100ForConditionalGeneration, M2M100Tokenizer
+
+>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
+>>> chinese_text = "不要插手巫師的事務, 因為他們是微妙的, 很快就會發怒."
+
+>>> tokenizer = M2M100Tokenizer.from_pretrained("facebook/m2m100_418M", src_lang="zh")
+>>> model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M")
+```
+
+对文本进行分词:
+
+```py
+>>> encoded_zh = tokenizer(chinese_text, return_tensors="pt")
+```
+
+M2M100 强制将目标语言 id 作为第一个生成的标记,以进行到目标语言的翻译。在 `generate` 方法中将 `forced_bos_token_id` 设置为 `en` 以翻译成英语:
+
+```py
+>>> generated_tokens = model.generate(**encoded_zh, forced_bos_token_id=tokenizer.get_lang_id("en"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+'Do not interfere with the matters of the witches, because they are delicate and will soon be angry.'
+```
+
+## MBart
+
+以下 MBart 模型可用于多语言翻译:
+
+- `facebook/mbart-large-50-one-to-many-mmt` (一对多多语言机器翻译,支持 50 种语言)
+- `facebook/mbart-large-50-many-to-many-mmt` (多对多多语言机器翻译,支持 50 种语言)
+- `facebook/mbart-large-50-many-to-one-mmt` (多对一多语言机器翻译,支持 50 种语言)
+- `facebook/mbart-large-50` (多语言翻译,支持 50 种语言)
+- `facebook/mbart-large-cc25`
+
+在此示例中,加载 `facebook/mbart-large-50-many-to-many-mmt` 检查点以将芬兰语翻译为英语。 你可以在分词器中设置源语言:
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
+>>> fi_text = "Älä sekaannu velhojen asioihin, sillä ne ovat hienovaraisia ja nopeasti vihaisia."
+
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/mbart-large-50-many-to-many-mmt", src_lang="fi_FI")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/mbart-large-50-many-to-many-mmt")
+```
+
+对文本进行分词:
+
+```py
+>>> encoded_en = tokenizer(en_text, return_tensors="pt")
+```
+
+MBart 强制将目标语言 id 作为第一个生成的标记,以进行到目标语言的翻译。在 `generate` 方法中将 `forced_bos_token_id` 设置为 `en` 以翻译成英语:
+
+```py
+>>> generated_tokens = model.generate(**encoded_en, forced_bos_token_id=tokenizer.lang_code_to_id["en_XX"])
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+"Don't interfere with the wizard's affairs, because they are subtle, will soon get angry."
+```
+
+如果你使用的是 `facebook/mbart-large-50-many-to-one-mmt` 检查点,则无需强制目标语言 id 作为第一个生成的令牌,否则用法是相同的。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/peft.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/peft.md
new file mode 100644
index 0000000000000000000000000000000000000000..de7ae6d1553c7fa1eef0dde8337998c401b9b4c7
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/peft.md
@@ -0,0 +1,215 @@
+
+
+# 使用 🤗 PEFT 加载adapters
+
+[[open-in-colab]]
+
+[参数高效微调(PEFT)方法](https://huggingface.co/blog/peft)在微调过程中冻结预训练模型的参数,并在其顶部添加少量可训练参数(adapters)。adapters被训练以学习特定任务的信息。这种方法已被证明非常节省内存,同时具有较低的计算使用量,同时产生与完全微调模型相当的结果。
+
+使用PEFT训练的adapters通常比完整模型小一个数量级,使其方便共享、存储和加载。
+
+
+
+
与完整尺寸的模型权重(约为700MB)相比,存储在Hub上的OPTForCausalLM模型的adapter权重仅为~6MB。
+
+
+你可以使用`AutoModelFor`类或基础模型类(如`OPTForCausalLM`或`LlamaForCausalLM`)来加载一个PEFT adapter。
+
+
+
+
+您也可以通过`load_adapter`方法来加载 PEFT adapter。
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_id = "facebook/opt-350m"
+peft_model_id = "ybelkada/opt-350m-lora"
+
+model = AutoModelForCausalLM.from_pretrained(model_id)
+model.load_adapter(peft_model_id)
+```
+
+## 基于8bit或4bit进行加载
+
+`bitsandbytes`集成支持8bit和4bit精度数据类型,这对于加载大模型非常有用,因为它可以节省内存(请参阅`bitsandbytes`[指南](./quantization#bitsandbytes-integration)以了解更多信息)。要有效地将模型分配到您的硬件,请在[`~PreTrainedModel.from_pretrained`]中添加`load_in_8bit`或`load_in_4bit`参数,并将`device_map="auto"`设置为:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+peft_model_id = "ybelkada/opt-350m-lora"
+model = AutoModelForCausalLM.from_pretrained(peft_model_id, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+```
+
+## 添加新的adapter
+
+你可以使用[`~peft.PeftModel.add_adapter`]方法为一个已有adapter的模型添加一个新的adapter,只要新adapter的类型与当前adapter相同即可。例如,如果你有一个附加到模型上的LoRA adapter:
+
+```py
+from transformers import AutoModelForCausalLM, OPTForCausalLM, AutoTokenizer
+from peft import PeftConfig
+
+model_id = "facebook/opt-350m"
+model = AutoModelForCausalLM.from_pretrained(model_id)
+
+lora_config = LoraConfig(
+ target_modules=["q_proj", "k_proj"],
+ init_lora_weights=False
+)
+
+model.add_adapter(lora_config, adapter_name="adapter_1")
+```
+
+
+添加一个新的adapter:
+
+```py
+# attach new adapter with same config
+model.add_adapter(lora_config, adapter_name="adapter_2")
+```
+现在您可以使用[`~peft.PeftModel.set_adapter`]来设置要使用的adapter。
+
+```py
+# use adapter_1
+model.set_adapter("adapter_1")
+output = model.generate(**inputs)
+print(tokenizer.decode(output_disabled[0], skip_special_tokens=True))
+
+# use adapter_2
+model.set_adapter("adapter_2")
+output_enabled = model.generate(**inputs)
+print(tokenizer.decode(output_enabled[0], skip_special_tokens=True))
+```
+
+## 启用和禁用adapters
+一旦您将adapter添加到模型中,您可以启用或禁用adapter模块。要启用adapter模块:
+
+
+```py
+from transformers import AutoModelForCausalLM, OPTForCausalLM, AutoTokenizer
+from peft import PeftConfig
+
+model_id = "facebook/opt-350m"
+adapter_model_id = "ybelkada/opt-350m-lora"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+text = "Hello"
+inputs = tokenizer(text, return_tensors="pt")
+
+model = AutoModelForCausalLM.from_pretrained(model_id)
+peft_config = PeftConfig.from_pretrained(adapter_model_id)
+
+# to initiate with random weights
+peft_config.init_lora_weights = False
+
+model.add_adapter(peft_config)
+model.enable_adapters()
+output = model.generate(**inputs)
+```
+要禁用adapter模块:
+
+```py
+model.disable_adapters()
+output = model.generate(**inputs)
+```
+## 训练一个 PEFT adapter
+
+PEFT适配器受[`Trainer`]类支持,因此您可以为您的特定用例训练适配器。它只需要添加几行代码即可。例如,要训练一个LoRA adapter:
+
+
+
+
+如果你不熟悉如何使用[`Trainer`]微调模型,请查看[微调预训练模型](training)教程。
+
+
+
+1. 使用任务类型和超参数定义adapter配置(参见[`~peft.LoraConfig`]以了解超参数的详细信息)。
+
+```py
+from peft import LoraConfig
+
+peft_config = LoraConfig(
+ lora_alpha=16,
+ lora_dropout=0.1,
+ r=64,
+ bias="none",
+ task_type="CAUSAL_LM",
+)
+```
+
+2. 将adapter添加到模型中。
+
+```py
+model.add_adapter(peft_config)
+```
+
+3. 现在可以将模型传递给[`Trainer`]了!
+
+```py
+trainer = Trainer(model=model, ...)
+trainer.train()
+```
+
+要保存训练好的adapter并重新加载它:
+
+```py
+model.save_pretrained(save_dir)
+model = AutoModelForCausalLM.from_pretrained(save_dir)
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/perf_hardware.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/perf_hardware.md
new file mode 100644
index 0000000000000000000000000000000000000000..95a09eaab4e10353d47d75b1ae7b3a27ba022e18
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/perf_hardware.md
@@ -0,0 +1,156 @@
+
+
+
+# 训练用的定制硬件
+
+您用来运行模型训练和推断的硬件可能会对性能产生重大影响。要深入了解 GPU,务必查看 Tim Dettmer 出色的[博文](https://timdettmers.com/2020/09/07/which-gpu-for-deep-learning/)。
+
+让我们来看一些关于 GPU 配置的实用建议。
+
+## GPU
+当你训练更大的模型时,基本上有三种选择:
+
+- 更大的 GPU
+- 更多的 GPU
+- 更多的 CPU 和 NVMe(通过[DeepSpeed-Infinity](main_classes/deepspeed#nvme-support)实现)
+
+让我们从只有一块GPU的情况开始。
+
+### 供电和散热
+
+如果您购买了昂贵的高端GPU,请确保为其提供正确的供电和足够的散热。
+
+**供电**:
+
+一些高端消费者级GPU卡具有2个,有时甚至3个PCI-E-8针电源插口。请确保将与插口数量相同的独立12V PCI-E-8针线缆插入卡中。不要使用同一根线缆两端的2个分叉(也称为pigtail cable)。也就是说,如果您的GPU上有2个插口,您需要使用2条PCI-E-8针线缆连接电源和卡,而不是使用一条末端有2个PCI-E-8针连接器的线缆!否则,您无法充分发挥卡的性能。
+
+每个PCI-E-8针电源线缆需要插入电源侧的12V轨上,并且可以提供最多150W的功率。
+
+其他一些卡可能使用PCI-E-12针连接器,这些连接器可以提供最多500-600W的功率。
+
+低端卡可能使用6针连接器,这些连接器可提供最多75W的功率。
+
+此外,您需要选择具有稳定电压的高端电源。一些质量较低的电源可能无法为卡提供所需的稳定电压以发挥其最大性能。
+
+当然,电源还需要有足够的未使用的瓦数来为卡供电。
+
+**散热**:
+
+当GPU过热时,它将开始降频,不会提供完整的性能。如果温度过高,可能会缩短GPU的使用寿命。
+
+当GPU负载很重时,很难确定最佳温度是多少,但任何低于+80度的温度都是好的,越低越好,也许在70-75度之间是一个非常好的范围。降频可能从大约84-90度开始。但是除了降频外,持续的高温可能会缩短GPU的使用寿命。
+
+接下来让我们看一下拥有多个GPU时最重要的方面之一:连接。
+
+### 多GPU连接
+
+如果您使用多个GPU,则卡之间的互连方式可能会对总训练时间产生巨大影响。如果GPU位于同一物理节点上,您可以运行以下代码:
+
+```bash
+nvidia-smi topo -m
+```
+
+它将告诉您GPU如何互连。在具有双GPU并通过NVLink连接的机器上,您最有可能看到类似以下内容:
+
+```
+ GPU0 GPU1 CPU Affinity NUMA Affinity
+GPU0 X NV2 0-23 N/A
+GPU1 NV2 X 0-23 N/A
+```
+
+在不同的机器上,如果没有NVLink,我们可能会看到:
+```
+ GPU0 GPU1 CPU Affinity NUMA Affinity
+GPU0 X PHB 0-11 N/A
+GPU1 PHB X 0-11 N/A
+```
+
+这个报告包括了这个输出:
+
+```
+ X = Self
+ SYS = Connection traversing PCIe as well as the SMP interconnect between NUMA nodes (e.g., QPI/UPI)
+ NODE = Connection traversing PCIe as well as the interconnect between PCIe Host Bridges within a NUMA node
+ PHB = Connection traversing PCIe as well as a PCIe Host Bridge (typically the CPU)
+ PXB = Connection traversing multiple PCIe bridges (without traversing the PCIe Host Bridge)
+ PIX = Connection traversing at most a single PCIe bridge
+ NV# = Connection traversing a bonded set of # NVLinks
+```
+
+因此,第一个报告`NV2`告诉我们GPU通过2个NVLink互连,而第二个报告`PHB`展示了典型的消费者级PCIe+Bridge设置。
+
+检查你的设置中具有哪种连接类型。其中一些会使卡之间的通信更快(例如NVLink),而其他则较慢(例如PHB)。
+
+根据使用的扩展解决方案的类型,连接速度可能会产生重大或较小的影响。如果GPU很少需要同步,就像在DDP中一样,那么较慢的连接的影响将不那么显著。如果GPU经常需要相互发送消息,就像在ZeRO-DP中一样,那么更快的连接对于实现更快的训练变得非常重要。
+
+
+#### NVlink
+
+[NVLink](https://en.wikipedia.org/wiki/NVLink)是由Nvidia开发的一种基于线缆的串行多通道近程通信链接。
+
+每个新一代提供更快的带宽,例如在[Nvidia Ampere GA102 GPU架构](https://www.nvidia.com/content/dam/en-zz/Solutions/geforce/ampere/pdf/NVIDIA-ampere-GA102-GPU-Architecture-Whitepaper-V1.pdf)中有这样的引述:
+
+> Third-Generation NVLink®
+> GA102 GPUs utilize NVIDIA’s third-generation NVLink interface, which includes four x4 links,
+> with each link providing 14.0625 GB/sec bandwidth in each direction between two GPUs. Four
+> links provide 56.25 GB/sec bandwidth in each direction, and 112.5 GB/sec total bandwidth
+> between two GPUs. Two RTX 3090 GPUs can be connected together for SLI using NVLink.
+> (Note that 3-Way and 4-Way SLI configurations are not supported.)
+
+所以,在`nvidia-smi topo -m`输出的`NVX`报告中获取到的更高的`X`值意味着更好的性能。生成的结果将取决于您的GPU架构。
+
+让我们比较在小样本wikitext上训练gpt2语言模型的执行结果。
+
+结果是:
+
+
+| NVlink | Time |
+| ----- | ---: |
+| Y | 101s |
+| N | 131s |
+
+
+可以看到,NVLink使训练速度提高了约23%。在第二个基准测试中,我们使用`NCCL_P2P_DISABLE=1`告诉GPU不要使用NVLink。
+
+这里是完整的基准测试代码和输出:
+
+```bash
+# DDP w/ NVLink
+
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 torchrun \
+--nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py --model_name_or_path openai-community/gpt2 \
+--dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 --do_train \
+--output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 101.9003, 'train_samples_per_second': 1.963, 'epoch': 0.69}
+
+# DDP w/o NVLink
+
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 NCCL_P2P_DISABLE=1 torchrun \
+--nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py --model_name_or_path openai-community/gpt2 \
+--dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 --do_train
+--output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 131.4367, 'train_samples_per_second': 1.522, 'epoch': 0.69}
+```
+
+硬件: 2x TITAN RTX 24GB each + NVlink with 2 NVLinks (`NV2` in `nvidia-smi topo -m`)
+软件: `pytorch-1.8-to-be` + `cuda-11.0` / `transformers==4.3.0.dev0`
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/perf_infer_gpu_multi.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/perf_infer_gpu_multi.md
new file mode 100644
index 0000000000000000000000000000000000000000..35e5bac465a33f29c1317fbff4002547d4ac2ae8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/perf_infer_gpu_multi.md
@@ -0,0 +1,68 @@
+
+
+# 多GPU推理
+
+某些模型现已支持内置的**张量并行**(Tensor Parallelism, TP),并通过 PyTorch 实现。张量并行技术将模型切分到多个 GPU 上,从而支持更大的模型尺寸,并对诸如矩阵乘法等计算任务进行并行化。
+
+要启用张量并行,只需在调用 [`~AutoModelForCausalLM.from_pretrained`] 时传递参数 `tp_plan="auto"`:
+
+```python
+import os
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_id = "meta-llama/Meta-Llama-3-8B-Instruct"
+
+# 初始化分布式环境
+rank = int(os.environ["RANK"])
+device = torch.device(f"cuda:{rank}")
+torch.distributed.init_process_group("nccl", device_id=device)
+
+# 获取支持张量并行的模型
+model = AutoModelForCausalLM.from_pretrained(
+ model_id,
+ tp_plan="auto",
+)
+
+# 准备输入tokens
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+prompt = "Can I help"
+inputs = tokenizer(prompt, return_tensors="pt").input_ids.to(device)
+
+# 分布式运行
+outputs = model(inputs)
+```
+
+您可以使用 `torchrun` 命令启动上述脚本,多进程模式会自动将每个进程映射到一张 GPU:
+
+```
+torchrun --nproc-per-node 4 demo.py
+```
+
+目前,PyTorch 张量并行支持以下模型:
+* [Llama](https://huggingface.co/docs/transformers/model_doc/llama#transformers.LlamaModel)
+
+如果您希望对其他模型添加张量并行支持,可以通过提交 GitHub Issue 或 Pull Request 来提出请求。
+
+### 预期性能提升
+
+对于推理场景(尤其是处理大批量或长序列的输入),张量并行可以显著提升计算速度。
+
+以下是 [Llama](https://huggingface.co/docs/transformers/model_doc/llama#transformers.LlamaModel) 模型在序列长度为 512 且不同批量大小情况下的单次前向推理的预期加速效果:
+
+
+
+
+
+
+
+
+
+
+
-f https://developer.intel.com/ipex-whl-stable-cpu
+```
+
+如果需要的话,您可以在 [ipex-whl-stable-cpu](https://developer.intel.com/ipex-whl-stable-cpu) 查看最新版本。
+
+查看更多 [安装IPEX](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/installation.html) 的方法。
+
+
+### 在 Trainer 中使用 IPEX
+在 Trainer 中使用 IPEX 时,您应在训练命令参数中添加 `use_ipex`、`bf16` 或 `fp16` 以及 `no_cuda` 来启用自动混合精度。
+
+以 [Transformers 问答任务](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)为例:
+
+- 在 CPU 上使用 BF16 自动混合精度训练 IPEX 的示例如下:
+ python examples/pytorch/question-answering/run_qa.py \
+--model_name_or_path google-bert/bert-base-uncased \
+--dataset_name squad \
+--do_train \
+--do_eval \
+--per_device_train_batch_size 12 \
+--learning_rate 3e-5 \
+--num_train_epochs 2 \
+--max_seq_length 384 \
+--doc_stride 128 \
+--output_dir /tmp/debug_squad/ \
+--use_ipex \
+--bf16 \
+--use_cpu
+
+如果您想在脚本中启用 `use_ipex` 和 `bf16`,请像下面这样将这些参数添加到 `TrainingArguments` 中:
+```diff
+training_args = TrainingArguments(
+ output_dir=args.output_path,
++ bf16=True,
++ use_ipex=True,
++ use_cpu=True,
+ **kwargs
+)
+```
+
+### 实践示例
+
+博客: [使用 Intel Sapphire Rapids 加速 PyTorch Transformers](https://huggingface.co/blog/intel-sapphire-rapids)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/perf_train_special.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/perf_train_special.md
new file mode 100644
index 0000000000000000000000000000000000000000..ee8553475679ee19d3c04fecb71f60924e11e731
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/perf_train_special.md
@@ -0,0 +1,58 @@
+
+
+# 在 Apple Silicon 芯片上进行 PyTorch 训练
+
+之前,在 Mac 上训练模型仅限于使用 CPU 训练。不过随着PyTorch v1.12的发布,您可以通过在 Apple Silicon 芯片的 GPU 上训练模型来显著提高性能和训练速度。这是通过将 Apple 的 Metal 性能着色器 (Metal Performance Shaders, MPS) 作为后端集成到PyTorch中实现的。[MPS后端](https://pytorch.org/docs/stable/notes/mps.html) 将 PyTorch 操作视为自定义的 Metal 着色器来实现,并将对应模块部署到`mps`设备上。
+
+
+
+某些 PyTorch 操作目前还未在 MPS 上实现,可能会抛出错误提示。可以通过设置环境变量`PYTORCH_ENABLE_MPS_FALLBACK=1`来使用CPU内核以避免这种情况发生(您仍然会看到一个`UserWarning`)。
+
+
+
+配置好`mps`设备后,您可以:
+
+* 在本地训练更大的网络或更大的批量大小
+* 降低数据获取延迟,因为 GPU 的统一内存架构允许直接访问整个内存存储
+* 降低成本,因为您不需要再在云端 GPU 上训练或增加额外的本地 GPU
+
+在确保已安装PyTorch后就可以开始使用了。 MPS 加速支持macOS 12.3及以上版本。
+
+```bash
+pip install torch torchvision torchaudio
+```
+
+[`TrainingArguments`]类默认使用`mps`设备(如果可用)因此无需显式设置设备。例如,您可以直接运行[run_glue.py](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-classification/run_glue.py)脚本,在无需进行任何修改的情况下自动启用 MPS 后端。
+
+```diff
+export TASK_NAME=mrpc
+
+python examples/pytorch/text-classification/run_glue.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --task_name $TASK_NAME \
+- --use_mps_device \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 32 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/ \
+ --overwrite_output_dir
+```
+
+用于[分布式设置](https://pytorch.org/docs/stable/distributed.html#backends)的后端(如`gloo`和`nccl`)不支持`mps`设备,这也意味着使用 MPS 后端时只能在单个 GPU 上进行训练。
+
+您可以在[Introducing Accelerated PyTorch Training on Mac](https://pytorch.org/blog/introducing-accelerated-pytorch-training-on-mac/)博客文章中了解有关 MPS 后端的更多信息。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/performance.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/performance.md
new file mode 100644
index 0000000000000000000000000000000000000000..afe41c8fdd14739de27b86891b2e49aaa2354c04
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/performance.md
@@ -0,0 +1,63 @@
+
+
+# 性能与可扩展性
+
+训练大型transformer模型并将其部署到生产环境会面临各种挑战。
+在训练过程中,模型可能需要比可用的GPU内存更多的资源,或者表现出较慢的训练速度。在部署阶段,模型可能在生产环境中难以处理所需的吞吐量。
+
+本文档旨在帮助您克服这些挑战,并找到适合您使用场景的最佳设置。教程分为训练和推理部分,因为每个部分都有不同的挑战和解决方案。在每个部分中,您将找到针对不同硬件配置的单独指南,例如单GPU与多GPU用于训练或CPU与GPU用于推理。
+
+将此文档作为您的起点,进一步导航到与您的情况匹配的方法。
+
+## 训练
+
+高效训练大型transformer模型需要使用加速器硬件,如GPU或TPU。最常见的情况是您只有一个GPU。您应用于单个GPU上提高训练效率的方法可以扩展到其他设置,如多个GPU。然而,也有一些特定于多GPU或CPU训练的技术。我们在单独的部分中介绍它们。
+
+* [在单个GPU上进行高效训练的方法和工具](perf_train_gpu_one):从这里开始学习常见的方法,可以帮助优化GPU内存利用率、加快训练速度或两者兼备。
+* [多GPU训练部分](perf_train_gpu_many):探索此部分以了解适用于多GPU设置的进一步优化方法,例如数据并行、张量并行和流水线并行。
+* [CPU训练部分](perf_train_cpu):了解在CPU上的混合精度训练。
+* [在多个CPU上进行高效训练](perf_train_cpu_many):了解分布式CPU训练。
+* [使用TensorFlow在TPU上进行训练](perf_train_tpu_tf):如果您对TPU还不熟悉,请参考此部分,了解有关在TPU上进行训练和使用XLA的建议性介绍。
+* [自定义硬件进行训练](perf_hardware):在构建自己的深度学习机器时查找技巧和窍门。
+* [使用Trainer API进行超参数搜索](hpo_train)
+
+
+## 推理
+
+在生产环境中对大型模型进行高效推理可能与训练它们一样具有挑战性。在接下来的部分中,我们将详细介绍如何在CPU和单/多GPU设置上进行推理的步骤。
+
+* [在单个CPU上进行推理](perf_infer_cpu)
+* [在单个GPU上进行推理](perf_infer_gpu_one)
+* [多GPU推理](perf_infer_gpu_one)
+* [TensorFlow模型的XLA集成](tf_xla)
+
+## 训练和推理
+
+在这里,您将找到适用于训练模型或使用它进行推理的技巧、窍门和技巧。
+
+* [实例化大型模型](big_models)
+* [解决性能问题](debugging)
+
+## 贡献
+
+这份文档还远远没有完成,还有很多需要添加的内容,所以如果你有补充或更正的内容,请毫不犹豫地提交一个PR(Pull Request),或者如果你不确定,可以创建一个Issue,我们可以在那里讨论细节。
+
+在做出贡献时,如果A比B更好,请尽量包含可重复的基准测试和(或)该信息来源的链接(除非它直接来自您)。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/philosophy.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/philosophy.md
new file mode 100644
index 0000000000000000000000000000000000000000..b0fd0a5167d448f134bc63df0e5d0d4169dab8de
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/philosophy.md
@@ -0,0 +1,67 @@
+
+
+
+
+# Transformers 的设计理念
+
+🤗 Transformers 是一个专为以下用户群体构建的库:
+
+- 寻求使用、研究或扩展大规模 Transformers 模型的机器学习研究人员和教育者。
+- 希望微调这些模型或在生产环境中使用它们(或两者兼而有之)的实际操作者。
+- 只想下载预训练模型并将其用于解决给定机器学习任务的工程师。
+
+Transformers 设计时有两个主要目标:
+
+1. 尽可能简单快速地使用:
+
+ - 我们尽可能地限制用户能接触的抽象层,实际上几乎没有抽象。用户只需学习三个标准类即可使用每个模型:[configuration](main_classes/configuration)、[models](main_classes/model) 和一个预处理类(用于 NLP 的 [tokenizer](main_classes/tokenizer),用于视觉的 [image processor](main_classes/image_processor),用于音频的 [feature extractor](main_classes/feature_extractor),以及用于多模态输入的 [processor](main_classes/processors))。
+ - 所有这些类都可以通过一个通用的 `from_pretrained()` 方法从预训练实例中简单统一地初始化,该方法会从提供在 [Hugging Face Hub](https://huggingface.co/models) 上的预训练检查点(如果需要的话)下载、缓存和加载相关类实例及相关数据(配置的超参数、分词器的词汇表和模型的权重)。
+ - 在这三个基本类之上,该库提供了两种 API:[`pipeline`] 用于快速在给定任务上使用模型进行推断,以及 [`Trainer`] 用于快速训练或微调 PyTorch 模型(所有 TensorFlow 模型与 `Keras.fit` 兼容)。
+ - 因此,Transformers 不是神经网络的模块化工具箱。如果要基于 Transformers 扩展或搭建新项目,请使用常规的 Python、PyTorch、TensorFlow、Keras 模块,并从 Transformers 的基类继承以重用模型加载和保存等功能。如果想了解更多有关我们的模型代码的设计理念,请查看我们的[重复自己](https://huggingface.co/blog/transformers-design-philosophy)博文。
+
+2. 提供与原始模型性能尽可能接近的最新模型:
+
+ - 我们为每种架构提供至少一个示例,复现了该架构官方作者提供的结果。
+ - 代码通常尽可能接近原始代码库,这意味着某些 PyTorch 代码可能不够*pytorchic*,因为它是转换后的 TensorFlow 代码,反之亦然。
+
+其他几个目标:
+
+- 尽可能一致地公开模型的内部:
+
+ - 我们使用单一 API 提供对完整隐藏状态和注意力权重的访问。
+ - 预处理类和基本模型 API 标准化,便于在不同模型之间轻松切换。
+
+- 结合主观选择的有前途的工具进行模型微调和调查:
+
+ - 简单一致的方法来向词汇表和嵌入中添加新标记以进行微调。
+ - 简单的方法来屏蔽和修剪 Transformer 头部。
+
+- 轻松在 PyTorch、TensorFlow 2.0 和 Flax 之间切换,允许使用一个框架进行训练并使用另一个进行推断。
+
+## 主要概念
+
+该库围绕每个模型的三类类构建:
+
+- **模型类** 可以是 PyTorch 模型([torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module))、Keras 模型([tf.keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model))或 JAX/Flax 模型([flax.linen.Module](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html)),这些模型可以使用库中提供的预训练权重。
+- **配置类** 存储构建模型所需的超参数(如层数和隐藏大小)。通常情况下,如果您使用不进行任何修改的预训练模型,则创建模型将自动处理配置的实例化(配置是模型的一部分)。
+- **预处理类** 将原始数据转换为模型可接受的格式。一个 [tokenizer](main_classes/tokenizer) 存储每个模型的词汇表,并提供编码和解码字符串为要馈送到模型的令牌嵌入索引列表的方法。[Image processors](main_classes/image_processor) 预处理视觉输入,[feature extractors](main_classes/feature_extractor) 预处理音频输入,而 [processor](main_classes/processors) 则处理多模态输入。
+
+所有这些类都可以从预训练实例中实例化、本地保存,并通过以下三种方法与 Hub 共享:
+
+- `from_pretrained()` 允许您从库自身提供的预训练版本(支持的模型可在 [Model Hub](https://huggingface.co/models) 上找到)或用户本地(或服务器上)存储的版本实例化模型、配置和预处理类。
+- `save_pretrained()` 允许您本地保存模型、配置和预处理类,以便可以使用 `from_pretrained()` 重新加载。
+- `push_to_hub()` 允许您将模型、配置和预处理类共享到 Hub,以便所有人都可以轻松访问。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/pipeline_tutorial.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/pipeline_tutorial.md
new file mode 100644
index 0000000000000000000000000000000000000000..ab2136022913f83f49139ad3502ee6c135c2ee2b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/pipeline_tutorial.md
@@ -0,0 +1,310 @@
+
+
+# 推理pipeline
+
+[`pipeline`] 让使用[Hub](https://huggingface.co/models)上的任何模型进行任何语言、计算机视觉、语音以及多模态任务的推理变得非常简单。即使您对特定的模态没有经验,或者不熟悉模型的源码,您仍然可以使用[`pipeline`]进行推理!本教程将教您:
+
+- 如何使用[`pipeline`] 进行推理。
+- 如何使用特定的`tokenizer`(分词器)或模型。
+- 如何使用[`pipeline`] 进行音频、视觉和多模态任务的推理。
+
+
+
+请查看[`pipeline`]文档以获取已支持的任务和可用参数的完整列表。
+
+
+
+## Pipeline使用
+
+虽然每个任务都有一个关联的[`pipeline`],但使用通用的抽象的[`pipeline`]更加简单,其中包含所有特定任务的`pipelines`。[`pipeline`]会自动加载一个默认模型和一个能够进行任务推理的预处理类。让我们以使用[`pipeline`]进行自动语音识别(ASR)或语音转文本为例。
+
+1. 首先,创建一个[`pipeline`]并指定推理任务:
+
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline(task="automatic-speech-recognition")
+```
+
+2. 将您的输入传递给[`pipeline`]。对于语音识别,这通常是一个音频输入文件:
+
+
+```py
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': 'I HAVE A DREAM BUT ONE DAY THIS NATION WILL RISE UP LIVE UP THE TRUE MEANING OF ITS TREES'}
+```
+
+您没有得到您期望的结果?可以在Hub上查看一些[最受欢迎的自动语音识别模型](https://huggingface.co/models?pipeline_tag=automatic-speech-recognition&sort=trending)
+,看看是否可以获得更好的转录。
+
+让我们尝试来自 OpenAI 的[Whisper large-v2](https://huggingface.co/openai/whisper-large) 模型。Whisperb比Wav2Vec2晚2年发布,使用接近10倍的数据进行了训练。因此,它在大多数下游基准测试上击败了Wav2Vec2。
+它还具有预测标点和大小写的附加优势,而Wav2Vec2则无法实现这些功能。
+
+让我们在这里尝试一下,看看它的表现如何:
+
+
+```py
+>>> transcriber = pipeline(model="openai/whisper-large-v2")
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
+```
+
+现在这个结果看起来更准确了!要进行深入的Wav2Vec2与Whisper比较,请参阅[音频变换器课程](https://huggingface.co/learn/audio-course/chapter5/asr_models)。
+我们鼓励您在 Hub 上查看不同语言的模型,以及专业领域的模型等。您可以在Hub上直接查看并比较模型的结果,以确定是否适合或处理边缘情况是否比其他模型更好。如果您没有找到适用于您的用例的模型,您始终可以[训练](training)自己的模型!
+
+如果您有多个输入,您可以将输入作为列表传递:
+
+
+```py
+transcriber(
+ [
+ "https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac",
+ "https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/1.flac",
+ ]
+)
+```
+
+`Pipelines`非常适合用于测试,因为从一个模型切换到另一个模型非常琐碎;但是,还有一些方法可以将它们优化后用于大型工作负载而不仅仅是测试。请查看以下指南,深入探讨如何迭代整个数据集或在Web服务器中使用`Pipelines`:
+* [在数据集上使用流水线](#using-pipelines-on-a-dataset)
+* [在Web服务器中使用流水线](./pipeline_webserver)
+
+
+## 参数
+
+[`pipeline`] 支持许多参数;有些是适用于特定任务的,而有些适用于所有`pipeline`。通常情况下,您可以在任何地方指定对应参数:
+
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", my_parameter=1)
+
+out = transcriber(...) # This will use `my_parameter=1`.
+out = transcriber(..., my_parameter=2) # This will override and use `my_parameter=2`.
+out = transcriber(...) # This will go back to using `my_parameter=1`.
+```
+
+让我们查看其中的三个重要参数:
+
+
+### 设备
+
+如果您使用 `device=n`,`pipeline`会自动将模型放在指定的设备上。无论您使用PyTorch还是Tensorflow,这都可以工作。
+
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", device=0)
+```
+
+如果模型对于单个GPU来说过于庞大,并且您正在使用PyTorch,您可以设置 `device_map="auto"` 以自动确定如何加载和存储模型权重。使用 `device_map` 参数需要安装🤗 [Accelerate](https://huggingface.co/docs/accelerate) 软件包:
+
+
+```bash
+pip install --upgrade accelerate
+```
+
+以下代码会自动在各个设备上加载和存储模型权重:
+
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", device_map="auto")
+```
+
+请注意,如果传递了 `device_map="auto"`,在实例化您的 `pipeline` 时不需要添加 `device=device` 参数,否则可能会遇到一些意外的状况!
+
+### 批量大小
+
+默认情况下,`pipelines`不会进行批量推理,原因在[这里](https://huggingface.co/docs/transformers/main_classes/pipelines#pipeline-batching)详细解释。因为批处理不一定更快,实际上在某些情况下可能会更慢。
+
+但如果在您的用例中起作用,您可以使用:
+
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", device=0, batch_size=2)
+audio_filenames = [f"https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/{i}.flac" for i in range(1, 5)]
+texts = transcriber(audio_filenames)
+```
+
+以上代码会在提供的4个音频文件上运行`pipeline`,它会将它们以2个一组的批次传递给模型(模型在GPU上,此时批处理更有可能有所帮助),而您无需编写额外的代码。输出应始终与没有批处理时收到的结果相一致。它只是一种帮助您更快地使用`pipeline`的方式。
+
+`pipeline`也可以减轻一些批处理的复杂性,因为对于某些`pipeline`,需要将单个项目(如长音频文件)分成多个部分以供模型处理。`pipeline`为您执行这种[*chunk batching*](./main_classes/pipelines#pipeline-chunk-batching)。
+
+### 任务特定参数
+
+所有任务都提供了特定于任务的参数,这些参数提供额外的灵活性和选择,以帮助您完成工作。
+例如,[`transformers.AutomaticSpeechRecognitionPipeline.__call__`] 方法具有一个 `return_timestamps` 参数,对于字幕视频似乎很有帮助:
+
+```py
+>>> transcriber = pipeline(model="openai/whisper-large-v2", return_timestamps=True)
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.', 'chunks': [{'timestamp': (0.0, 11.88), 'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its'}, {'timestamp': (11.88, 12.38), 'text': ' creed.'}]}
+```
+
+正如您所看到的,模型推断出了文本,还输出了各个句子发音的**时间**。
+
+每个任务都有许多可用的参数,因此请查看每个任务的API参考,以了解您可以进行哪些调整!例如,[`~transformers.AutomaticSpeechRecognitionPipeline`] 具有 `chunk_length_s` 参数,对于处理非常长的音频文件(例如,为整部电影或长达一小时的视频配字幕)非常有帮助,这通常是模型无法单独处理的:
+
+```python
+>>> transcriber = pipeline(model="openai/whisper-large-v2", chunk_length_s=30, return_timestamps=True)
+>>> transcriber("https://huggingface.co/datasets/sanchit-gandhi/librispeech_long/resolve/main/audio.wav")
+{'text': " Chapter 16. I might have told you of the beginning of this liaison in a few lines, but I wanted you to see every step by which we came. I, too, agree to whatever Marguerite wished, Marguerite to be unable to live apart from me. It was the day after the evening...
+```
+
+如果您找不到一个真正有帮助的参数,欢迎[提出请求](https://github.com/huggingface/transformers/issues/new?assignees=&labels=feature&template=feature-request.yml)!
+
+## 在数据集上使用pipelines
+
+`pipelines`也可以对大型数据集进行推理。我们建议使用迭代器来完成这一任务,这是最简单的方法:
+
+
+```py
+def data():
+ for i in range(1000):
+ yield f"My example {i}"
+
+
+pipe = pipeline(model="openai-community/gpt2", device=0)
+generated_characters = 0
+for out in pipe(data()):
+ generated_characters += len(out[0]["generated_text"])
+```
+
+迭代器 `data()` 会产生每个结果,`pipelines`会自动识别输入为可迭代对象,并在GPU上处理数据的同时开始获取数据(在底层使用[DataLoader](https://pytorch.org/docs/stable/data.html#torch.utils.data.DataLoader))。这一点非常重要,因为您不必为整个数据集分配内存,可以尽可能快地将数据传送到GPU。
+
+由于批处理可以加速处理,因此在这里尝试调整 `batch_size` 参数可能会很有用。
+
+迭代数据集的最简单方法就是从🤗 [Datasets](https://github.com/huggingface/datasets/) 中加载数据集:
+
+
+```py
+# KeyDataset is a util that will just output the item we're interested in.
+from transformers.pipelines.pt_utils import KeyDataset
+from datasets import load_dataset
+
+pipe = pipeline(model="hf-internal-testing/tiny-random-wav2vec2", device=0)
+dataset = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation[:10]")
+
+for out in pipe(KeyDataset(dataset, "audio")):
+ print(out)
+```
+
+
+## 在Web服务器上使用pipelines
+
+
+创建推理引擎是一个复杂的主题,值得有自己的页面。
+
+
+[链接](./pipeline_webserver)
+
+## 视觉流水线
+
+对于视觉任务,使用[`pipeline`] 几乎是相同的。
+
+指定您的任务并将图像传递给分类器。图像可以是链接、本地路径或base64编码的图像。例如,下面显示的是哪种品种的猫?
+
+
+```py
+>>> from transformers import pipeline
+
+>>> vision_classifier = pipeline(model="google/vit-base-patch16-224")
+>>> preds = vision_classifier(
+... images="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.4335, 'label': 'lynx, catamount'}, {'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}, {'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}, {'score': 0.0239, 'label': 'Egyptian cat'}, {'score': 0.0229, 'label': 'tiger cat'}]
+```
+
+## 文本流水线
+
+对于NLP任务,使用[`pipeline`] 几乎是相同的。
+
+
+```py
+>>> from transformers import pipeline
+
+>>> # This model is a `zero-shot-classification` model.
+>>> # It will classify text, except you are free to choose any label you might imagine
+>>> classifier = pipeline(model="facebook/bart-large-mnli")
+>>> classifier(
+... "I have a problem with my iphone that needs to be resolved asap!!",
+... candidate_labels=["urgent", "not urgent", "phone", "tablet", "computer"],
+... )
+{'sequence': 'I have a problem with my iphone that needs to be resolved asap!!', 'labels': ['urgent', 'phone', 'computer', 'not urgent', 'tablet'], 'scores': [0.504, 0.479, 0.013, 0.003, 0.002]}
+```
+
+## 多模态流水线
+
+[`pipeline`] 支持多个模态。例如,视觉问题回答(VQA)任务结合了文本和图像。请随意使用您喜欢的任何图像链接和您想要问关于该图像的问题。图像可以是URL或图像的本地路径。
+
+例如,如果您使用这个[invoice image](https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png):
+
+
+```py
+>>> from transformers import pipeline
+
+>>> vqa = pipeline(model="impira/layoutlm-document-qa")
+>>> output = vqa(
+... image="https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png",
+... question="What is the invoice number?",
+... )
+>>> output[0]["score"] = round(output[0]["score"], 3)
+>>> output
+[{'score': 0.425, 'answer': 'us-001', 'start': 16, 'end': 16}]
+```
+
+
+
+要运行上面的示例,除了🤗 Transformers之外,您需要安装[`pytesseract`](https://pypi.org/project/pytesseract/)。
+
+
+```bash
+sudo apt install -y tesseract-ocr
+pip install pytesseract
+```
+
+
+
+## 在大模型上使用🤗 `accelerate`和`pipeline`:
+
+您可以轻松地使用🤗 `accelerate`在大模型上运行 `pipeline`!首先确保您已经使用 `pip install accelerate` 安装了 `accelerate`。
+
+首先使用 `device_map="auto"` 加载您的模型!我们将在示例中使用 `facebook/opt-1.3b`。
+
+
+```py
+# pip install accelerate
+import torch
+from transformers import pipeline
+
+pipe = pipeline(model="facebook/opt-1.3b", torch_dtype=torch.bfloat16, device_map="auto")
+output = pipe("This is a cool example!", do_sample=True, top_p=0.95)
+```
+
+如果安装 `bitsandbytes` 并添加参数 `load_in_8bit=True`,您还可以传递8位加载的模型。
+
+
+```py
+# pip install accelerate bitsandbytes
+import torch
+from transformers import pipeline
+
+pipe = pipeline(model="facebook/opt-1.3b", device_map="auto", model_kwargs={"load_in_8bit": True})
+output = pipe("This is a cool example!", do_sample=True, top_p=0.95)
+```
+
+请注意,您可以将`checkpoint `替换为任何支持大模型加载的Hugging Face模型,比如BLOOM!
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/preprocessing.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/preprocessing.md
new file mode 100644
index 0000000000000000000000000000000000000000..b90c89b36d1567b7bf778889db25c4750519d03d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/preprocessing.md
@@ -0,0 +1,541 @@
+
+
+# 预处理
+
+[[open-in-colab]]
+
+在您可以在数据集上训练模型之前,数据需要被预处理为期望的模型输入格式。无论您的数据是文本、图像还是音频,它们都需要被转换并组合成批量的张量。🤗 Transformers 提供了一组预处理类来帮助准备数据以供模型使用。在本教程中,您将了解以下内容:
+
+* 对于文本,使用[分词器](./main_classes/tokenizer)(`Tokenizer`)将文本转换为一系列标记(`tokens`),并创建`tokens`的数字表示,将它们组合成张量。
+* 对于语音和音频,使用[特征提取器](./main_classes/feature_extractor)(`Feature extractor`)从音频波形中提取顺序特征并将其转换为张量。
+* 图像输入使用[图像处理器](./main_classes/image)(`ImageProcessor`)将图像转换为张量。
+* 多模态输入,使用[处理器](./main_classes/processors)(`Processor`)结合了`Tokenizer`和`ImageProcessor`或`Processor`。
+
+
+
+`AutoProcessor` **始终**有效的自动选择适用于您使用的模型的正确`class`,无论您使用的是`Tokenizer`、`ImageProcessor`、`Feature extractor`还是`Processor`。
+
+
+
+在开始之前,请安装🤗 Datasets,以便您可以加载一些数据集来进行实验:
+
+
+```bash
+pip install datasets
+```
+
+## 自然语言处理
+
+
+
+如果您计划使用预训练模型,重要的是使用与之关联的预训练`Tokenizer`。这确保文本的拆分方式与预训练语料库相同,并在预训练期间使用相同的标记-索引的对应关系(通常称为*词汇表*-`vocab`)。
+
+
+
+开始使用[`AutoTokenizer.from_pretrained`]方法加载一个预训练`tokenizer`。这将下载模型预训练的`vocab`:
+
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-cased")
+```
+
+然后将您的文本传递给`tokenizer`:
+
+
+```py
+>>> encoded_input = tokenizer("Do not meddle in the affairs of wizards, for they are subtle and quick to anger.")
+>>> print(encoded_input)
+{'input_ids': [101, 2079, 2025, 19960, 10362, 1999, 1996, 3821, 1997, 16657, 1010, 2005, 2027, 2024, 11259, 1998, 4248, 2000, 4963, 1012, 102],
+ 'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+`tokenizer`返回一个包含三个重要对象的字典:
+
+* [input_ids](glossary#input-ids) 是与句子中每个`token`对应的索引。
+* [attention_mask](glossary#attention-mask) 指示是否应该关注一个`token`。
+* [token_type_ids](glossary#token-type-ids) 在存在多个序列时标识一个`token`属于哪个序列。
+
+通过解码 `input_ids` 来返回您的输入:
+
+
+```py
+>>> tokenizer.decode(encoded_input["input_ids"])
+'[CLS] Do not meddle in the affairs of wizards, for they are subtle and quick to anger. [SEP]'
+```
+
+如您所见,`tokenizer`向句子中添加了两个特殊`token` - `CLS` 和 `SEP`(分类器和分隔符)。并非所有模型都需要特殊`token`,但如果需要,`tokenizer`会自动为您添加。
+
+如果有多个句子需要预处理,将它们作为列表传递给`tokenizer`:
+
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_inputs = tokenizer(batch_sentences)
+>>> print(encoded_inputs)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1]]}
+```
+
+### 填充
+
+句子的长度并不总是相同,这可能会成为一个问题,因为模型输入的张量需要具有统一的形状。填充是一种策略,通过在较短的句子中添加一个特殊的`padding token`,以确保张量是矩形的。
+
+将 `padding` 参数设置为 `True`,以使批次中较短的序列填充到与最长序列相匹配的长度:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True)
+>>> print(encoded_input)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]]}
+```
+
+第一句和第三句因为较短,通过`0`进行填充,。
+
+### 截断
+
+另一方面,有时候一个序列可能对模型来说太长了。在这种情况下,您需要将序列截断为更短的长度。
+
+将 `truncation` 参数设置为 `True`,以将序列截断为模型接受的最大长度:
+
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True)
+>>> print(encoded_input)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]]}
+```
+
+
+
+查看[填充和截断](./pad_truncation)概念指南,了解更多有关填充和截断参数的信息。
+
+
+
+### 构建张量
+
+最后,`tokenizer`可以返回实际输入到模型的张量。
+
+将 `return_tensors` 参数设置为 `pt`(对于PyTorch)或 `tf`(对于TensorFlow):
+
+
+
+
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True, return_tensors="pt")
+>>> print(encoded_input)
+{'input_ids': tensor([[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]]),
+ 'token_type_ids': tensor([[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]]),
+ 'attention_mask': tensor([[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]])}
+```
+
+
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True, return_tensors="tf")
+>>> print(encoded_input)
+{'input_ids': ,
+ 'token_type_ids': ,
+ 'attention_mask': }
+```
+
+
+
+## 音频
+
+对于音频任务,您需要[feature extractor](main_classes/feature_extractor)来准备您的数据集以供模型使用。`feature extractor`旨在从原始音频数据中提取特征,并将它们转换为张量。
+
+加载[MInDS-14](https://huggingface.co/datasets/PolyAI/minds14)数据集(有关如何加载数据集的更多详细信息,请参阅🤗 [Datasets教程](https://huggingface.co/docs/datasets/load_hub))以了解如何在音频数据集中使用`feature extractor`:
+
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train")
+```
+
+访问 `audio` 列的第一个元素以查看输入。调用 `audio` 列会自动加载和重新采样音频文件:
+
+```py
+>>> dataset[0]["audio"]
+{'array': array([ 0. , 0.00024414, -0.00024414, ..., -0.00024414,
+ 0. , 0. ], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~JOINT_ACCOUNT/602ba55abb1e6d0fbce92065.wav',
+ 'sampling_rate': 8000}
+```
+
+这会返回三个对象:
+
+* `array` 是加载的语音信号 - 并在必要时重新采为`1D array`。
+* `path` 指向音频文件的位置。
+* `sampling_rate` 是每秒测量的语音信号数据点数量。
+
+对于本教程,您将使用[Wav2Vec2](https://huggingface.co/facebook/wav2vec2-base)模型。查看模型卡片,您将了解到Wav2Vec2是在16kHz采样的语音音频数据上预训练的。重要的是,您的音频数据的采样率要与用于预训练模型的数据集的采样率匹配。如果您的数据的采样率不同,那么您需要对数据进行重新采样。
+
+1. 使用🤗 Datasets的[`~datasets.Dataset.cast_column`]方法将采样率提升到16kHz:
+
+```py
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16_000))
+```
+
+2. 再次调用 `audio` 列以重新采样音频文件:
+
+
+```py
+>>> dataset[0]["audio"]
+{'array': array([ 2.3443763e-05, 2.1729663e-04, 2.2145823e-04, ...,
+ 3.8356509e-05, -7.3497440e-06, -2.1754686e-05], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~JOINT_ACCOUNT/602ba55abb1e6d0fbce92065.wav',
+ 'sampling_rate': 16000}
+```
+
+接下来,加载一个`feature extractor`以对输入进行标准化和填充。当填充文本数据时,会为较短的序列添加 `0`。相同的理念适用于音频数据。`feature extractor`添加 `0` - 被解释为静音 - 到`array` 。
+
+使用 [`AutoFeatureExtractor.from_pretrained`] 加载`feature extractor`:
+
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2-base")
+```
+
+将音频 `array` 传递给`feature extractor`。我们还建议在`feature extractor`中添加 `sampling_rate` 参数,以更好地调试可能发生的静音错误:
+
+
+```py
+>>> audio_input = [dataset[0]["audio"]["array"]]
+>>> feature_extractor(audio_input, sampling_rate=16000)
+{'input_values': [array([ 3.8106556e-04, 2.7506407e-03, 2.8015103e-03, ...,
+ 5.6335266e-04, 4.6588284e-06, -1.7142107e-04], dtype=float32)]}
+```
+
+就像`tokenizer`一样,您可以应用填充或截断来处理批次中的可变序列。请查看这两个音频样本的序列长度:
+
+
+```py
+>>> dataset[0]["audio"]["array"].shape
+(173398,)
+
+>>> dataset[1]["audio"]["array"].shape
+(106496,)
+```
+
+创建一个函数来预处理数据集,以使音频样本具有相同的长度。通过指定最大样本长度,`feature extractor`将填充或截断序列以使其匹配:
+
+
+```py
+>>> def preprocess_function(examples):
+... audio_arrays = [x["array"] for x in examples["audio"]]
+... inputs = feature_extractor(
+... audio_arrays,
+... sampling_rate=16000,
+... padding=True,
+... max_length=100000,
+... truncation=True,
+... )
+... return inputs
+```
+
+将`preprocess_function`应用于数据集中的前几个示例:
+
+
+```py
+>>> processed_dataset = preprocess_function(dataset[:5])
+```
+
+现在样本长度是相同的,并且与指定的最大长度匹配。您现在可以将经过处理的数据集传递给模型了!
+
+
+```py
+>>> processed_dataset["input_values"][0].shape
+(100000,)
+
+>>> processed_dataset["input_values"][1].shape
+(100000,)
+```
+
+## 计算机视觉
+
+对于计算机视觉任务,您需要一个[ image processor](main_classes/image_processor)来准备数据集以供模型使用。图像预处理包括多个步骤将图像转换为模型期望输入的格式。这些步骤包括但不限于调整大小、标准化、颜色通道校正以及将图像转换为张量。
+
+
+
+图像预处理通常遵循某种形式的图像增强。图像预处理和图像增强都会改变图像数据,但它们有不同的目的:
+
+* 图像增强可以帮助防止过拟合并增加模型的鲁棒性。您可以在数据增强方面充分发挥创造性 - 调整亮度和颜色、裁剪、旋转、调整大小、缩放等。但要注意不要改变图像的含义。
+* 图像预处理确保图像与模型预期的输入格式匹配。在微调计算机视觉模型时,必须对图像进行与模型训练时相同的预处理。
+
+您可以使用任何您喜欢的图像增强库。对于图像预处理,请使用与模型相关联的`ImageProcessor`。
+
+
+
+加载[food101](https://huggingface.co/datasets/food101)数据集(有关如何加载数据集的更多详细信息,请参阅🤗 [Datasets教程](https://huggingface.co/docs/datasets/load_hub))以了解如何在计算机视觉数据集中使用图像处理器:
+
+
+
+因为数据集相当大,请使用🤗 Datasets的`split`参数加载训练集中的少量样本!
+
+
+
+
+```py
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("food101", split="train[:100]")
+```
+
+接下来,使用🤗 Datasets的[`Image`](https://huggingface.co/docs/datasets/package_reference/main_classes?highlight=image#datasets.Image)功能查看图像:
+
+
+```py
+>>> dataset[0]["image"]
+```
+
+
+
+
+
+在上面的示例中,我们设置`do_resize=False`,因为我们已经在图像增强转换中调整了图像的大小,并利用了适当的`image_processor`的`size`属性。如果您在图像增强期间不调整图像的大小,请将此参数排除在外。默认情况下`ImageProcessor`将处理调整大小。
+
+如果希望将图像标准化步骤为图像增强的一部分,请使用`image_processor.image_mean`和`image_processor.image_std`。
+
+
+
+3. 然后使用🤗 Datasets的[`set_transform`](https://huggingface.co/docs/datasets/process#format-transform)在运行时应用这些变换:
+
+
+```py
+>>> dataset.set_transform(transforms)
+```
+
+4. 现在,当您访问图像时,您将注意到`image processor`已添加了 `pixel_values`。您现在可以将经过处理的数据集传递给模型了!
+
+
+```py
+>>> dataset[0].keys()
+```
+
+这是在应用变换后的图像样子。图像已被随机裁剪,并其颜色属性发生了变化。
+
+
+```py
+>>> import numpy as np
+>>> import matplotlib.pyplot as plt
+
+>>> img = dataset[0]["pixel_values"]
+>>> plt.imshow(img.permute(1, 2, 0))
+```
+
+
+
+
+
+对于诸如目标检测、语义分割、实例分割和全景分割等任务,`ImageProcessor`提供了训练后处理方法。这些方法将模型的原始输出转换为有意义的预测,如边界框或分割地图。
+
+
+
+### 填充
+
+在某些情况下,例如,在微调[DETR](./model_doc/detr)时,模型在训练时应用了尺度增强。这可能导致批处理中的图像大小不同。您可以使用[`DetrImageProcessor.pad`]来指定自定义的`collate_fn`将图像批处理在一起。
+
+```py
+>>> def collate_fn(batch):
+... pixel_values = [item["pixel_values"] for item in batch]
+... encoding = image_processor.pad(pixel_values, return_tensors="pt")
+... labels = [item["labels"] for item in batch]
+... batch = {}
+... batch["pixel_values"] = encoding["pixel_values"]
+... batch["pixel_mask"] = encoding["pixel_mask"]
+... batch["labels"] = labels
+... return batch
+```
+
+## 多模态
+
+对于涉及多模态输入的任务,您需要[processor](main_classes/processors)来为模型准备数据集。`processor`将两个处理对象-例如`tokenizer`和`feature extractor`-组合在一起。
+
+加载[LJ Speech](https://huggingface.co/datasets/lj_speech)数据集(有关如何加载数据集的更多详细信息,请参阅🤗 [Datasets 教程](https://huggingface.co/docs/datasets/load_hub))以了解如何使用`processor`进行自动语音识别(ASR):
+
+
+```py
+>>> from datasets import load_dataset
+
+>>> lj_speech = load_dataset("lj_speech", split="train")
+```
+
+对于ASR(自动语音识别),主要关注`audio`和`text`,因此可以删除其他列:
+
+
+```py
+>>> lj_speech = lj_speech.map(remove_columns=["file", "id", "normalized_text"])
+```
+
+现在查看`audio`和`text`列:
+
+```py
+>>> lj_speech[0]["audio"]
+{'array': array([-7.3242188e-04, -7.6293945e-04, -6.4086914e-04, ...,
+ 7.3242188e-04, 2.1362305e-04, 6.1035156e-05], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/917ece08c95cf0c4115e45294e3cd0dee724a1165b7fc11798369308a465bd26/LJSpeech-1.1/wavs/LJ001-0001.wav',
+ 'sampling_rate': 22050}
+
+>>> lj_speech[0]["text"]
+'Printing, in the only sense with which we are at present concerned, differs from most if not from all the arts and crafts represented in the Exhibition'
+```
+
+请记住,您应始终[重新采样](preprocessing#audio)音频数据集的采样率,以匹配用于预训练模型数据集的采样率!
+
+
+```py
+>>> lj_speech = lj_speech.cast_column("audio", Audio(sampling_rate=16_000))
+```
+
+使用[`AutoProcessor.from_pretrained`]加载一个`processor`:
+
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base-960h")
+```
+
+1. 创建一个函数,用于将包含在 `array` 中的音频数据处理为 `input_values`,并将 `text` 标记为 `labels`。这些将是输入模型的数据:
+
+```py
+>>> def prepare_dataset(example):
+... audio = example["audio"]
+
+... example.update(processor(audio=audio["array"], text=example["text"], sampling_rate=16000))
+
+... return example
+```
+
+2. 将 `prepare_dataset` 函数应用于一个示例:
+
+```py
+>>> prepare_dataset(lj_speech[0])
+```
+
+`processor`现在已经添加了 `input_values` 和 `labels`,并且采样率也正确降低为为16kHz。现在可以将处理后的数据集传递给模型!
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/quicktour.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/quicktour.md
new file mode 100644
index 0000000000000000000000000000000000000000..0c3fc8b8571dd87ac97232eca366a8199783ce04
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/quicktour.md
@@ -0,0 +1,547 @@
+
+
+# 快速上手
+
+[[open-in-colab]]
+
+快来使用 🤗 Transformers 吧!无论你是开发人员还是日常用户,这篇快速上手教程都将帮助你入门并且向你展示如何使用 [`pipeline`] 进行推理,使用 [AutoClass](./model_doc/auto) 加载一个预训练模型和预处理器,以及使用 PyTorch 或 TensorFlow 快速训练一个模型。如果你是一个初学者,我们建议你接下来查看我们的教程或者[课程](https://huggingface.co/course/chapter1/1),来更深入地了解在这里介绍到的概念。
+
+在开始之前,确保你已经安装了所有必要的库:
+
+```bash
+!pip install transformers datasets evaluate accelerate
+```
+
+你还需要安装喜欢的机器学习框架:
+
+
+
+
+```bash
+pip install torch
+```
+
+
+
+```bash
+pip install tensorflow
+```
+
+
+
+## Pipeline
+
+
+
+使用 [`AutoModelForSequenceClassification`] 和 [`AutoTokenizer`] 来加载预训练模型和它关联的分词器(更多信息可以参考下一节的 `AutoClass`):
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+使用 [`TFAutoModelForSequenceClassification`] 和 [`AutoTokenizer`] 来加载预训练模型和它关联的分词器(更多信息可以参考下一节的 `TFAutoClass`):
+
+```py
+>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+
+在 [`pipeline`] 中指定模型和分词器,现在你就可以在法语文本上使用 `classifier` 了:
+
+```py
+>>> classifier = pipeline("sentiment-analysis", model=model, tokenizer=tokenizer)
+>>> classifier("Nous sommes très heureux de vous présenter la bibliothèque 🤗 Transformers.")
+[{'label': '5 stars', 'score': 0.7273}]
+```
+
+如果你没有找到适合你的模型,就需要在你的数据上微调一个预训练模型了。查看 [微调教程](./training) 来学习怎样进行微调。最后,微调完模型后,考虑一下在 Hub 上与社区 [分享](./model_sharing) 这个模型,把机器学习普及到每一个人! 🤗
+
+## AutoClass
+
+
+
+
+```py
+>>> pt_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="pt",
+... )
+```
+
+
+
+```py
+>>> tf_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="tf",
+... )
+```
+
+
+
+
+
+查阅[预处理](./preprocessing)教程来获得有关分词的更详细的信息,以及如何使用 [`AutoFeatureExtractor`] 和 [`AutoProcessor`] 来处理图像,音频,还有多模式输入。
+
+
+
+### AutoModel
+
+
+
+🤗 Transformers 提供了一种简单统一的方式来加载预训练的实例. 这表示你可以像加载 [`AutoTokenizer`] 一样加载 [`AutoModel`]。唯一不同的地方是为你的任务选择正确的[`AutoModel`]。对于文本(或序列)分类,你应该加载[`AutoModelForSequenceClassification`]:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+通过 [任务摘要](./task_summary) 查找 [`AutoModel`] 支持的任务.
+
+
+
+现在可以把预处理好的输入批次直接送进模型。你只需要通过 `**` 来解包字典:
+
+```py
+>>> pt_outputs = pt_model(**pt_batch)
+```
+
+模型在 `logits` 属性输出最终的激活结果. 在 `logits` 上应用 softmax 函数来查询概率:
+
+```py
+>>> from torch import nn
+
+>>> pt_predictions = nn.functional.softmax(pt_outputs.logits, dim=-1)
+>>> print(pt_predictions)
+tensor([[0.0021, 0.0018, 0.0115, 0.2121, 0.7725],
+ [0.2084, 0.1826, 0.1969, 0.1755, 0.2365]], grad_fn=)
+```
+
+
+🤗 Transformers 提供了一种简单统一的方式来加载预训练的实例。这表示你可以像加载 [`AutoTokenizer`] 一样加载 [`TFAutoModel`]。唯一不同的地方是为你的任务选择正确的 [`TFAutoModel`],对于文本(或序列)分类,你应该加载 [`TFAutoModelForSequenceClassification`]:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+通过 [任务摘要](./task_summary) 查找 [`AutoModel`] 支持的任务.
+
+
+
+现在通过直接将字典的键传给张量,将预处理的输入批次传给模型。
+
+```py
+>>> tf_outputs = tf_model(tf_batch)
+```
+
+模型在 `logits` 属性输出最终的激活结果。在 `logits` 上应用softmax函数来查询概率:
+
+```py
+>>> import tensorflow as tf
+
+>>> tf_predictions = tf.nn.softmax(tf_outputs.logits, axis=-1)
+>>> tf_predictions # doctest: +IGNORE_RESULT
+```
+
+
+
+
+
+所有 🤗 Transformers 模型(PyTorch 或 TensorFlow)在最终的激活函数(比如 softmax)*之前* 输出张量,
+因为最终的激活函数常常与 loss 融合。模型的输出是特殊的数据类,所以它们的属性可以在 IDE 中被自动补全。模型的输出就像一个元组或字典(你可以通过整数、切片或字符串来索引它),在这种情况下,为 None 的属性会被忽略。
+
+
+
+### 保存模型
+
+
+
+当你的模型微调完成,你就可以使用 [`PreTrainedModel.save_pretrained`] 把它和它的分词器保存下来:
+
+```py
+>>> pt_save_directory = "./pt_save_pretrained"
+>>> tokenizer.save_pretrained(pt_save_directory) # doctest: +IGNORE_RESULT
+>>> pt_model.save_pretrained(pt_save_directory)
+```
+
+当你准备再次使用这个模型时,就可以使用 [`PreTrainedModel.from_pretrained`] 加载它了:
+
+```py
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained("./pt_save_pretrained")
+```
+
+
+当你的模型微调完成,你就可以使用 [`TFPreTrainedModel.save_pretrained`] 把它和它的分词器保存下来:
+
+```py
+>>> tf_save_directory = "./tf_save_pretrained"
+>>> tokenizer.save_pretrained(tf_save_directory) # doctest: +IGNORE_RESULT
+>>> tf_model.save_pretrained(tf_save_directory)
+```
+
+当你准备再次使用这个模型时,就可以使用 [`TFPreTrainedModel.from_pretrained`] 加载它了:
+
+```py
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("./tf_save_pretrained")
+```
+
+
+
+🤗 Transformers 有一个特别酷的功能,它能够保存一个模型,并且将它加载为 PyTorch 或 TensorFlow 模型。`from_pt` 或 `from_tf` 参数可以将模型从一个框架转换为另一个框架:
+
+
+
+
+```py
+>>> from transformers import AutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(pt_save_directory)
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(pt_save_directory, from_pt=True)
+```
+
+
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(tf_save_directory)
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(tf_save_directory, from_tf=True)
+```
+
+
+
+## 自定义模型构建
+
+你可以修改模型的配置类来改变模型的构建方式。配置指明了模型的属性,比如隐藏层或者注意力头的数量。当你从自定义的配置类初始化模型时,你就开始自定义模型构建了。模型属性是随机初始化的,你需要先训练模型,然后才能得到有意义的结果。
+
+通过导入 [`AutoConfig`] 来开始,之后加载你想修改的预训练模型。在 [`AutoConfig.from_pretrained`] 中,你能够指定想要修改的属性,比如注意力头的数量:
+
+```py
+>>> from transformers import AutoConfig
+
+>>> my_config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased", n_heads=12)
+```
+
+
+
+使用 [`AutoModel.from_config`] 根据你的自定义配置创建一个模型:
+
+```py
+>>> from transformers import AutoModel
+
+>>> my_model = AutoModel.from_config(my_config)
+```
+
+
+使用 [`TFAutoModel.from_config`] 根据你的自定义配置创建一个模型:
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> my_model = TFAutoModel.from_config(my_config)
+```
+
+
+
+查阅 [创建一个自定义结构](./create_a_model) 指南获取更多关于构建自定义配置的信息。
+
+## Trainer - PyTorch 优化训练循环
+
+所有的模型都是标准的 [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module),所以你可以在任何典型的训练模型中使用它们。当你编写自己的训练循环时,🤗 Transformers 为 PyTorch 提供了一个 [`Trainer`] 类,它包含了基础的训练循环并且为诸如分布式训练,混合精度等特性增加了额外的功能。
+
+取决于你的任务, 你通常可以传递以下的参数给 [`Trainer`]:
+
+1. [`PreTrainedModel`] 或者 [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module):
+
+ ```py
+ >>> from transformers import AutoModelForSequenceClassification
+
+ >>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+2. [`TrainingArguments`] 含有你可以修改的模型超参数,比如学习率,批次大小和训练时的迭代次数。如果你没有指定训练参数,那么它会使用默认值:
+
+ ```py
+ >>> from transformers import TrainingArguments
+
+ >>> training_args = TrainingArguments(
+ ... output_dir="path/to/save/folder/",
+ ... learning_rate=2e-5,
+ ... per_device_train_batch_size=8,
+ ... per_device_eval_batch_size=8,
+ ... num_train_epochs=2,
+ ... )
+ ```
+
+3. 一个预处理类,比如分词器,特征提取器或者处理器:
+
+ ```py
+ >>> from transformers import AutoTokenizer
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+4. 加载一个数据集:
+
+ ```py
+ >>> from datasets import load_dataset
+
+ >>> dataset = load_dataset("rotten_tomatoes") # doctest: +IGNORE_RESULT
+ ```
+
+5. 创建一个给数据集分词的函数,并且使用 [`~datasets.Dataset.map`] 应用到整个数据集:
+
+ ```py
+ >>> def tokenize_dataset(dataset):
+ ... return tokenizer(dataset["text"])
+
+ >>> dataset = dataset.map(tokenize_dataset, batched=True)
+ ```
+
+6. 用来从数据集中创建批次的 [`DataCollatorWithPadding`]:
+
+ ```py
+ >>> from transformers import DataCollatorWithPadding
+
+ >>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
+ ```
+
+现在把所有的类传给 [`Trainer`]:
+
+```py
+>>> from transformers import Trainer
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=dataset["train"],
+... eval_dataset=dataset["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... ) # doctest: +SKIP
+```
+
+一切准备就绪后,调用 [`~Trainer.train`] 进行训练:
+
+```py
+>>> trainer.train() # doctest: +SKIP
+```
+
+
+
+对于像翻译或摘要这些使用序列到序列模型的任务,用 [`Seq2SeqTrainer`] 和 [`Seq2SeqTrainingArguments`] 来替代。
+
+
+
+你可以通过子类化 [`Trainer`] 中的方法来自定义训练循环。这样你就可以自定义像损失函数,优化器和调度器这样的特性。查阅 [`Trainer`] 参考手册了解哪些方法能够被子类化。
+
+另一个自定义训练循环的方式是通过[回调](./main_classes/callback)。你可以使用回调来与其他库集成,查看训练循环来报告进度或提前结束训练。回调不会修改训练循环。如果想自定义损失函数等,就需要子类化 [`Trainer`] 了。
+
+## 使用 Tensorflow 训练
+
+所有模型都是标准的 [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model),所以你可以通过 [Keras](https://keras.io/) API 实现在 Tensorflow 中训练。🤗 Transformers 提供了 [`~TFPreTrainedModel.prepare_tf_dataset`] 方法来轻松地将数据集加载为 `tf.data.Dataset`,这样你就可以使用 Keras 的 [`compile`](https://keras.io/api/models/model_training_apis/#compile-method) 和 [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) 方法马上开始训练。
+
+1. 使用 [`TFPreTrainedModel`] 或者 [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) 来开始:
+
+ ```py
+ >>> from transformers import TFAutoModelForSequenceClassification
+
+ >>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+2. 一个预处理类,比如分词器,特征提取器或者处理器:
+
+ ```py
+ >>> from transformers import AutoTokenizer
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+3. 创建一个给数据集分词的函数
+
+ ```py
+ >>> def tokenize_dataset(dataset):
+ ... return tokenizer(dataset["text"]) # doctest: +SKIP
+ ```
+
+4. 使用 [`~datasets.Dataset.map`] 将分词器应用到整个数据集,之后将数据集和分词器传给 [`~TFPreTrainedModel.prepare_tf_dataset`]。如果你需要的话,也可以在这里改变批次大小和是否打乱数据集:
+
+ ```py
+ >>> dataset = dataset.map(tokenize_dataset) # doctest: +SKIP
+ >>> tf_dataset = model.prepare_tf_dataset(
+ ... dataset, batch_size=16, shuffle=True, tokenizer=tokenizer
+ ... ) # doctest: +SKIP
+ ```
+
+5. 一切准备就绪后,调用 `compile` 和 `fit` 开始训练:
+
+ ```py
+ >>> from tensorflow.keras.optimizers import Adam
+
+ >>> model.compile(optimizer=Adam(3e-5))
+ >>> model.fit(dataset) # doctest: +SKIP
+ ```
+
+## 接下来做什么?
+
+现在你已经完成了 🤗 Transformers 的快速上手教程,来看看我们的指南并且学习如何做一些更具体的事情,比如写一个自定义模型,为某个任务微调一个模型以及如何使用脚本来训练模型。如果你有兴趣了解更多 🤗 Transformers 的核心章节,那就喝杯咖啡然后来看看我们的概念指南吧!
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/run_scripts.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/run_scripts.md
new file mode 100644
index 0000000000000000000000000000000000000000..d058e97d1ad5879941b011d6b9980d2be7f3ebd3
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/run_scripts.md
@@ -0,0 +1,359 @@
+
+
+# 使用脚本进行训练
+
+除了 🤗 Transformers [notebooks](./notebooks),还有示例脚本演示了如何使用[PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch)、[TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow)或[JAX/Flax](https://github.com/huggingface/transformers/tree/main/examples/flax)训练模型以解决特定任务。
+
+您还可以在这些示例中找到我们在[研究项目](https://github.com/huggingface/transformers/tree/main/examples/research_projects)和[遗留示例](https://github.com/huggingface/transformers/tree/main/examples/legacy)中使用过的脚本,这些脚本主要是由社区贡献的。这些脚本已不再被积极维护,需要使用特定版本的🤗 Transformers, 可能与库的最新版本不兼容。
+
+示例脚本可能无法在初始配置下直接解决每个问题,您可能需要根据要解决的问题调整脚本。为了帮助您,大多数脚本都完全暴露了数据预处理的方式,允许您根据需要对其进行编辑。
+
+如果您想在示例脚本中实现任何功能,请在[论坛](https://discuss.huggingface.co/)或[issue](https://github.com/huggingface/transformers/issues)上讨论,然后再提交Pull Request。虽然我们欢迎修复错误,但不太可能合并添加更多功能的Pull Request,因为这会降低可读性。
+
+本指南将向您展示如何在[PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization)和[TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/summarization)中运行示例摘要训练脚本。除非另有说明,否则所有示例都可以在两个框架中工作。
+
+## 设置
+
+要成功运行示例脚本的最新版本,您必须在新虚拟环境中**从源代码安装 🤗 Transformers**:
+
+```bash
+git clone https://github.com/huggingface/transformers
+cd transformers
+pip install .
+```
+
+对于旧版本的示例脚本,请点击下面的切换按钮:
+
+
+ 老版本🤗 Transformers示例
+
+
+
+然后切换您clone的 🤗 Transformers 仓到特定的版本,例如v3.5.1:
+
+```bash
+git checkout tags/v3.5.1
+```
+
+在安装了正确的库版本后,进入您选择的版本的`example`文件夹并安装例子要求的环境:
+
+```bash
+pip install -r requirements.txt
+```
+
+## 运行脚本
+
+
+
+
+示例脚本从🤗 [Datasets](https://huggingface.co/docs/datasets/)库下载并预处理数据集。然后,脚本通过[Trainer](https://huggingface.co/docs/transformers/main_classes/trainer)使用支持摘要任务的架构对数据集进行微调。以下示例展示了如何在[CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail)数据集上微调[T5-small](https://huggingface.co/google-t5/t5-small)。由于T5模型的训练方式,它需要一个额外的`source_prefix`参数。这个提示让T5知道这是一个摘要任务。
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+
+示例脚本从 🤗 [Datasets](https://huggingface.co/docs/datasets/) 库下载并预处理数据集。然后,脚本使用 Keras 在支持摘要的架构上微调数据集。以下示例展示了如何在 [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail) 数据集上微调 [T5-small](https://huggingface.co/google-t5/t5-small)。T5 模型由于训练方式需要额外的 `source_prefix` 参数。这个提示让 T5 知道这是一个摘要任务。
+
+```bash
+python examples/tensorflow/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## 分布式训练和混合精度
+
+[Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) 支持分布式训练和混合精度,这意味着你也可以在脚本中使用它。要启用这两个功能,可以做如下设置:
+
+- 添加 `fp16` 参数以启用混合精度。
+- 使用 `nproc_per_node` 参数设置使用的GPU数量。
+
+
+```bash
+torchrun \
+ --nproc_per_node 8 pytorch/summarization/run_summarization.py \
+ --fp16 \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+TensorFlow脚本使用[`MirroredStrategy`](https://www.tensorflow.org/guide/distributed_training#mirroredstrategy)进行分布式训练,您无需在训练脚本中添加任何其他参数。如果可用,TensorFlow脚本将默认使用多个GPU。
+
+## 在TPU上运行脚本
+
+
+
+
+张量处理单元(TPUs)是专门设计用于加速性能的。PyTorch使用[XLA](https://www.tensorflow.org/xla)深度学习编译器支持TPU(更多细节请参见[这里](https://github.com/pytorch/xla/blob/master/README.md))。要使用TPU,请启动`xla_spawn.py`脚本并使用`num_cores`参数设置要使用的TPU核心数量。
+
+```bash
+python xla_spawn.py --num_cores 8 \
+ summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+
+张量处理单元(TPUs)是专门设计用于加速性能的。TensorFlow脚本使用[`TPUStrategy`](https://www.tensorflow.org/guide/distributed_training#tpustrategy)在TPU上进行训练。要使用TPU,请将TPU资源的名称传递给`tpu`参数。
+
+```bash
+python run_summarization.py \
+ --tpu name_of_tpu_resource \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## 基于🤗 Accelerate运行脚本
+
+🤗 [Accelerate](https://huggingface.co/docs/accelerate) 是一个仅支持 PyTorch 的库,它提供了一种统一的方法来在不同类型的设置(仅 CPU、多个 GPU、多个TPU)上训练模型,同时保持对 PyTorch 训练循环的完全可见性。如果你还没有安装 🤗 Accelerate,请确保你已经安装了它:
+
+> 注意:由于 Accelerate 正在快速发展,因此必须安装 git 版本的 accelerate 来运行脚本。
+
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+你需要使用`run_summarization_no_trainer.py`脚本,而不是`run_summarization.py`脚本。🤗 Accelerate支持的脚本需要在文件夹中有一个`task_no_trainer.py`文件。首先运行以下命令以创建并保存配置文件:
+
+```bash
+accelerate config
+```
+检测您的设置以确保配置正确:
+
+```bash
+accelerate test
+```
+
+现在您可以开始训练模型了:
+
+```bash
+accelerate launch run_summarization_no_trainer.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir ~/tmp/tst-summarization
+```
+
+## 使用自定义数据集
+
+摘要脚本支持自定义数据集,只要它们是CSV或JSON Line文件。当你使用自己的数据集时,需要指定一些额外的参数:
+- `train_file` 和 `validation_file` 分别指定您的训练和验证文件的路径。
+- `text_column` 是输入要进行摘要的文本。
+- `summary_column` 是目标输出的文本。
+
+使用自定义数据集的摘要脚本看起来是这样的:
+
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --train_file path_to_csv_or_jsonlines_file \
+ --validation_file path_to_csv_or_jsonlines_file \
+ --text_column text_column_name \
+ --summary_column summary_column_name \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --overwrite_output_dir \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --predict_with_generate
+```
+
+## 测试脚本
+
+通常,在提交整个数据集之前,最好先在较少的数据集示例上运行脚本,以确保一切按预期工作,因为完整数据集的处理可能需要花费几个小时的时间。使用以下参数将数据集截断为最大样本数:
+
+- `max_train_samples`
+- `max_eval_samples`
+- `max_predict_samples`
+
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --max_train_samples 50 \
+ --max_eval_samples 50 \
+ --max_predict_samples 50 \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+并非所有示例脚本都支持`max_predict_samples`参数。如果您不确定您的脚本是否支持此参数,请添加`-h`参数进行检查:
+
+```bash
+examples/pytorch/summarization/run_summarization.py -h
+```
+
+## 从checkpoint恢复训练
+
+另一个有用的选项是从之前的checkpoint恢复训练。这将确保在训练中断时,您可以从之前停止的地方继续进行,而无需重新开始。有两种方法可以从checkpoint恢复训练。
+
+第一种方法使用`output_dir previous_output_dir`参数从存储在`output_dir`中的最新的checkpoint恢复训练。在这种情况下,您应该删除`overwrite_output_dir`:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --output_dir previous_output_dir \
+ --predict_with_generate
+```
+
+第二种方法使用`resume_from_checkpoint path_to_specific_checkpoint`参数从特定的checkpoint文件夹恢复训练。
+
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --resume_from_checkpoint path_to_specific_checkpoint \
+ --predict_with_generate
+```
+
+## 分享模型
+
+所有脚本都可以将您的最终模型上传到[Model Hub](https://huggingface.co/models)。在开始之前,请确保您已登录Hugging Face:
+
+```bash
+huggingface-cli login
+```
+
+然后,在脚本中添加`push_to_hub`参数。这个参数会创建一个带有您Hugging Face用户名和`output_dir`中指定的文件夹名称的仓库。
+
+为了给您的仓库指定一个特定的名称,使用`push_to_hub_model_id`参数来添加它。该仓库将自动列出在您的命名空间下。
+
+以下示例展示了如何上传具有特定仓库名称的模型:
+
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --push_to_hub \
+ --push_to_hub_model_id finetuned-t5-cnn_dailymail \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/serialization.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/serialization.md
new file mode 100644
index 0000000000000000000000000000000000000000..b9cc74e5849d630510930015c8b61d8e27960875
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/serialization.md
@@ -0,0 +1,181 @@
+
+
+# 导出为 ONNX
+
+在生产环境中部署 🤗 Transformers 模型通常需要或者能够受益于,将模型导出为可在专门的运行时和硬件上加载和执行的序列化格式。
+
+🤗 Optimum 是 Transformers 的扩展,可以通过其 `exporters` 模块将模型从 PyTorch 或 TensorFlow 导出为 ONNX 及 TFLite 等序列化格式。🤗 Optimum 还提供了一套性能优化工具,可以在目标硬件上以最高效率训练和运行模型。
+
+本指南演示了如何使用 🤗 Optimum 将 🤗 Transformers 模型导出为 ONNX。有关将模型导出为 TFLite 的指南,请参考 [导出为 TFLite 页面](tflite)。
+
+## 导出为 ONNX
+
+[ONNX (Open Neural Network eXchange 开放神经网络交换)](http://onnx.ai) 是一个开放的标准,它定义了一组通用的运算符和一种通用的文件格式,用于表示包括 PyTorch 和 TensorFlow 在内的各种框架中的深度学习模型。当一个模型被导出为 ONNX时,这些运算符被用于构建计算图(通常被称为*中间表示*),该图表示数据在神经网络中的流动。
+
+通过公开具有标准化运算符和数据类型的图,ONNX使得模型能够轻松在不同深度学习框架间切换。例如,在 PyTorch 中训练的模型可以被导出为 ONNX,然后再导入到 TensorFlow(反之亦然)。
+
+导出为 ONNX 后,模型可以:
+- 通过 [图优化(graph optimization)](https://huggingface.co/docs/optimum/onnxruntime/usage_guides/optimization) 和 [量化(quantization)](https://huggingface.co/docs/optimum/onnxruntime/usage_guides/quantization) 等技术进行推理优化。
+- 通过 [`ORTModelForXXX` 类](https://huggingface.co/docs/optimum/onnxruntime/package_reference/modeling_ort) 使用 ONNX Runtime 运行,它同样遵循你熟悉的 Transformers 中的 `AutoModel` API。
+- 使用 [优化推理流水线(pipeline)](https://huggingface.co/docs/optimum/main/en/onnxruntime/usage_guides/pipelines) 运行,其 API 与 🤗 Transformers 中的 [`pipeline`] 函数相同。
+
+🤗 Optimum 通过利用配置对象提供对 ONNX 导出的支持。多种模型架构已经有现成的配置对象,并且配置对象也被设计得易于扩展以适用于其他架构。
+
+现有的配置列表请参考 [🤗 Optimum 文档](https://huggingface.co/docs/optimum/exporters/onnx/overview)。
+
+有两种方式可以将 🤗 Transformers 模型导出为 ONNX,这里我们展示这两种方法:
+
+- 使用 🤗 Optimum 的 CLI(命令行)导出。
+- 使用 🤗 Optimum 的 `optimum.onnxruntime` 模块导出。
+
+### 使用 CLI 将 🤗 Transformers 模型导出为 ONNX
+
+要将 🤗 Transformers 模型导出为 ONNX,首先需要安装额外的依赖项:
+
+```bash
+pip install optimum[exporters]
+```
+
+请参阅 [🤗 Optimum 文档](https://huggingface.co/docs/optimum/exporters/onnx/usage_guides/export_a_model#exporting-a-model-to-onnx-using-the-cli) 以查看所有可用参数,或者在命令行中查看帮助:
+
+```bash
+optimum-cli export onnx --help
+```
+
+运行以下命令,以从 🤗 Hub 导出模型的检查点(checkpoint),以 `distilbert/distilbert-base-uncased-distilled-squad` 为例:
+
+```bash
+optimum-cli export onnx --model distilbert/distilbert-base-uncased-distilled-squad distilbert_base_uncased_squad_onnx/
+```
+
+你应该能在日志中看到导出进度以及生成的 `model.onnx` 文件的保存位置,如下所示:
+
+```bash
+Validating ONNX model distilbert_base_uncased_squad_onnx/model.onnx...
+ -[✓] ONNX model output names match reference model (start_logits, end_logits)
+ - Validating ONNX Model output "start_logits":
+ -[✓] (2, 16) matches (2, 16)
+ -[✓] all values close (atol: 0.0001)
+ - Validating ONNX Model output "end_logits":
+ -[✓] (2, 16) matches (2, 16)
+ -[✓] all values close (atol: 0.0001)
+The ONNX export succeeded and the exported model was saved at: distilbert_base_uncased_squad_onnx
+```
+
+上面的示例说明了从 🤗 Hub 导出检查点的过程。导出本地模型时,首先需要确保将模型的权重和分词器文件保存在同一目录(`local_path`)中。在使用 CLI 时,将 `local_path` 传递给 `model` 参数,而不是 🤗 Hub 上的检查点名称,并提供 `--task` 参数。你可以在 [🤗 Optimum 文档](https://huggingface.co/docs/optimum/exporters/task_manager)中查看支持的任务列表。如果未提供 `task` 参数,将默认导出不带特定任务头的模型架构。
+
+```bash
+optimum-cli export onnx --model local_path --task question-answering distilbert_base_uncased_squad_onnx/
+```
+
+生成的 `model.onnx` 文件可以在支持 ONNX 标准的 [许多加速引擎(accelerators)](https://onnx.ai/supported-tools.html#deployModel) 之一上运行。例如,我们可以使用 [ONNX Runtime](https://onnxruntime.ai/) 加载和运行模型,如下所示:
+
+```python
+>>> from transformers import AutoTokenizer
+>>> from optimum.onnxruntime import ORTModelForQuestionAnswering
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert_base_uncased_squad_onnx")
+>>> model = ORTModelForQuestionAnswering.from_pretrained("distilbert_base_uncased_squad_onnx")
+>>> inputs = tokenizer("What am I using?", "Using DistilBERT with ONNX Runtime!", return_tensors="pt")
+>>> outputs = model(**inputs)
+```
+
+从 Hub 导出 TensorFlow 检查点的过程也一样。例如,以下是从 [Keras 组织](https://huggingface.co/keras-io) 导出纯 TensorFlow 检查点的命令:
+
+```bash
+optimum-cli export onnx --model keras-io/transformers-qa distilbert_base_cased_squad_onnx/
+```
+
+### 使用 `optimum.onnxruntime` 将 🤗 Transformers 模型导出为 ONNX
+
+除了 CLI 之外,你还可以使用代码将 🤗 Transformers 模型导出为 ONNX,如下所示:
+
+```python
+>>> from optimum.onnxruntime import ORTModelForSequenceClassification
+>>> from transformers import AutoTokenizer
+
+>>> model_checkpoint = "distilbert_base_uncased_squad"
+>>> save_directory = "onnx/"
+
+>>> # 从 transformers 加载模型并将其导出为 ONNX
+>>> ort_model = ORTModelForSequenceClassification.from_pretrained(model_checkpoint, export=True)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_checkpoint)
+
+>>> # 保存 onnx 模型以及分词器
+>>> ort_model.save_pretrained(save_directory)
+>>> tokenizer.save_pretrained(save_directory)
+```
+
+### 导出尚未支持的架构的模型
+
+如果你想要为当前无法导出的模型添加支持,请先检查 [`optimum.exporters.onnx`](https://huggingface.co/docs/optimum/exporters/onnx/overview) 是否支持该模型,如果不支持,你可以 [直接为 🤗 Optimum 贡献代码](https://huggingface.co/docs/optimum/exporters/onnx/usage_guides/contribute)。
+
+### 使用 `transformers.onnx` 导出模型
+
+
+
+`tranformers.onnx` 不再进行维护,请如上所述,使用 🤗 Optimum 导出模型。这部分内容将在未来版本中删除。
+
+
+
+要使用 `tranformers.onnx` 将 🤗 Transformers 模型导出为 ONNX,请安装额外的依赖项:
+
+```bash
+pip install transformers[onnx]
+```
+
+将 `transformers.onnx` 包作为 Python 模块使用,以使用现成的配置导出检查点:
+
+```bash
+python -m transformers.onnx --model=distilbert/distilbert-base-uncased onnx/
+```
+
+以上代码将导出由 `--model` 参数定义的检查点的 ONNX 图。传入任何 🤗 Hub 上或者存储与本地的检查点。生成的 `model.onnx` 文件可以在支持 ONNX 标准的众多加速引擎上运行。例如,使用 ONNX Runtime 加载并运行模型,如下所示:
+
+```python
+>>> from transformers import AutoTokenizer
+>>> from onnxruntime import InferenceSession
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> session = InferenceSession("onnx/model.onnx")
+>>> # ONNX Runtime expects NumPy arrays as input
+>>> inputs = tokenizer("Using DistilBERT with ONNX Runtime!", return_tensors="np")
+>>> outputs = session.run(output_names=["last_hidden_state"], input_feed=dict(inputs))
+```
+
+可以通过查看每个模型的 ONNX 配置来获取所需的输出名(例如 `["last_hidden_state"]`)。例如,对于 DistilBERT,可以用以下代码获取输出名称:
+
+```python
+>>> from transformers.models.distilbert import DistilBertConfig, DistilBertOnnxConfig
+
+>>> config = DistilBertConfig()
+>>> onnx_config = DistilBertOnnxConfig(config)
+>>> print(list(onnx_config.outputs.keys()))
+["last_hidden_state"]
+```
+
+从 Hub 导出 TensorFlow 检查点的过程也一样。导出纯 TensorFlow 检查点的示例代码如下:
+
+```bash
+python -m transformers.onnx --model=keras-io/transformers-qa onnx/
+```
+
+要导出本地存储的模型,请将模型的权重和分词器文件保存在同一目录中(例如 `local-pt-checkpoint`),然后通过将 `transformers.onnx` 包的 `--model` 参数指向该目录,将其导出为 ONNX:
+
+```bash
+python -m transformers.onnx --model=local-pt-checkpoint onnx/
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/task_summary.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/task_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..cd6c30b93a07962b196f7c1ed14d0a78401a6393
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/task_summary.md
@@ -0,0 +1,345 @@
+
+
+# 🤗 Transformers 能做什么
+
+🤗 Transformers是一个用于自然语言处理(NLP)、计算机视觉和音频和语音处理任务的预训练模型库。该库不仅包含Transformer模型,还包括用于计算机视觉任务的现代卷积网络等非Transformer模型。如果您看看今天最受欢迎的一些消费产品,比如智能手机、应用程序和电视,很可能背后都有某种深度学习技术的支持。想要从您智能手机拍摄的照片中删除背景对象吗?这里是一个全景分割任务的例子(如果您还不了解这是什么意思,我们将在以下部分进行描述!)。
+
+本页面提供了使用🤗 Transformers库仅用三行代码解决不同的语音和音频、计算机视觉和NLP任务的概述!
+
+
+## 音频
+音频和语音处理任务与其他模态略有不同,主要是因为音频作为输入是一个连续的信号。与文本不同,原始音频波形不能像句子可以被划分为单词那样被整齐地分割成离散的块。为了解决这个问题,通常在固定的时间间隔内对原始音频信号进行采样。如果在每个时间间隔内采样更多样本,采样率就会更高,音频更接近原始音频源。
+
+以前的方法是预处理音频以从中提取有用的特征。现在更常见的做法是直接将原始音频波形输入到特征编码器中,以提取音频表示。这样可以简化预处理步骤,并允许模型学习最重要的特征。
+
+### 音频分类
+
+音频分类是一项将音频数据从预定义的类别集合中进行标记的任务。这是一个广泛的类别,具有许多具体的应用,其中一些包括:
+
+* 声学场景分类:使用场景标签("办公室"、"海滩"、"体育场")对音频进行标记。
+* 声学事件检测:使用声音事件标签("汽车喇叭声"、"鲸鱼叫声"、"玻璃破碎声")对音频进行标记。
+* 标记:对包含多种声音的音频进行标记(鸟鸣、会议中的说话人识别)。
+* 音乐分类:使用流派标签("金属"、"嘻哈"、"乡村")对音乐进行标记。
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="audio-classification", model="superb/hubert-base-superb-er")
+>>> preds = classifier("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.4532, 'label': 'hap'},
+ {'score': 0.3622, 'label': 'sad'},
+ {'score': 0.0943, 'label': 'neu'},
+ {'score': 0.0903, 'label': 'ang'}]
+```
+
+### 自动语音识别
+
+自动语音识别(ASR)将语音转录为文本。这是最常见的音频任务之一,部分原因是因为语音是人类交流的自然形式。如今,ASR系统嵌入在智能技术产品中,如扬声器、电话和汽车。我们可以要求虚拟助手播放音乐、设置提醒和告诉我们天气。
+
+但是,Transformer架构帮助解决的一个关键挑战是低资源语言。通过在大量语音数据上进行预训练,仅在一个低资源语言的一小时标记语音数据上进行微调,仍然可以产生与以前在100倍更多标记数据上训练的ASR系统相比高质量的结果。
+
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline(task="automatic-speech-recognition", model="openai/whisper-small")
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
+```
+
+## 计算机视觉
+
+计算机视觉任务中最早成功之一是使用卷积神经网络([CNN](glossary#convolution))识别邮政编码数字图像。图像由像素组成,每个像素都有一个数值。这使得将图像表示为像素值矩阵变得容易。每个像素值组合描述了图像的颜色。
+
+计算机视觉任务可以通过以下两种通用方式解决:
+
+1. 使用卷积来学习图像的层次特征,从低级特征到高级抽象特征。
+2. 将图像分成块,并使用Transformer逐步学习每个图像块如何相互关联以形成图像。与CNN偏好的自底向上方法不同,这种方法有点像从一个模糊的图像开始,然后逐渐将其聚焦清晰。
+
+### 图像分类
+
+图像分类将整个图像从预定义的类别集合中进行标记。像大多数分类任务一样,图像分类有许多实际用例,其中一些包括:
+
+* 医疗保健:标记医学图像以检测疾病或监测患者健康状况
+* 环境:标记卫星图像以监测森林砍伐、提供野外管理信息或检测野火
+* 农业:标记农作物图像以监测植物健康或用于土地使用监测的卫星图像
+* 生态学:标记动物或植物物种的图像以监测野生动物种群或跟踪濒危物种
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="image-classification")
+>>> preds = classifier(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> print(*preds, sep="\n")
+{'score': 0.4335, 'label': 'lynx, catamount'}
+{'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}
+{'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}
+{'score': 0.0239, 'label': 'Egyptian cat'}
+{'score': 0.0229, 'label': 'tiger cat'}
+```
+
+### 目标检测
+
+与图像分类不同,目标检测在图像中识别多个对象以及这些对象在图像中的位置(由边界框定义)。目标检测的一些示例应用包括:
+
+* 自动驾驶车辆:检测日常交通对象,如其他车辆、行人和红绿灯
+* 遥感:灾害监测、城市规划和天气预报
+* 缺陷检测:检测建筑物中的裂缝或结构损坏,以及制造业产品缺陷
+
+
+```py
+>>> from transformers import pipeline
+
+>>> detector = pipeline(task="object-detection")
+>>> preds = detector(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"], "box": pred["box"]} for pred in preds]
+>>> preds
+[{'score': 0.9865,
+ 'label': 'cat',
+ 'box': {'xmin': 178, 'ymin': 154, 'xmax': 882, 'ymax': 598}}]
+```
+
+### 图像分割
+
+图像分割是一项像素级任务,将图像中的每个像素分配给一个类别。它与使用边界框标记和预测图像中的对象的目标检测不同,因为分割更加精细。分割可以在像素级别检测对象。有几种类型的图像分割:
+
+* 实例分割:除了标记对象的类别外,还标记每个对象的不同实例(“dog-1”,“dog-2”)
+* 全景分割:语义分割和实例分割的组合; 它使用语义类为每个像素标记并标记每个对象的不同实例
+
+分割任务对于自动驾驶车辆很有帮助,可以创建周围世界的像素级地图,以便它们可以在行人和其他车辆周围安全导航。它还适用于医学成像,其中任务的更精细粒度可以帮助识别异常细胞或器官特征。图像分割也可以用于电子商务,通过您的相机在现实世界中覆盖物体来虚拟试穿衣服或创建增强现实体验。
+
+```py
+>>> from transformers import pipeline
+
+>>> segmenter = pipeline(task="image-segmentation")
+>>> preds = segmenter(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> print(*preds, sep="\n")
+{'score': 0.9879, 'label': 'LABEL_184'}
+{'score': 0.9973, 'label': 'snow'}
+{'score': 0.9972, 'label': 'cat'}
+```
+
+### 深度估计
+
+深度估计预测图像中每个像素到相机的距离。这个计算机视觉任务对于场景理解和重建尤为重要。例如,在自动驾驶汽车中,车辆需要了解行人、交通标志和其他车辆等物体的距离,以避免障碍物和碰撞。深度信息还有助于从2D图像构建3D表示,并可用于创建生物结构或建筑物的高质量3D表示。
+
+有两种方法可以进行深度估计:
+
+* stereo(立体):通过比较同一图像的两个略微不同角度的图像来估计深度
+* monocular(单目):从单个图像中估计深度
+
+
+```py
+>>> from transformers import pipeline
+
+>>> depth_estimator = pipeline(task="depth-estimation")
+>>> preds = depth_estimator(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+```
+
+## 自然语言处理
+
+NLP任务是最常见的类型之一,因为文本是我们进行交流的自然方式。为了让文本变成模型识别的格式,需要对其进行分词。这意味着将一段文本分成单独的单词或子词(`tokens`),然后将这些`tokens`转换为数字。因此,可以将一段文本表示为一系列数字,一旦有了一系列的数字,就可以将其输入到模型中以解决各种NLP任务!
+
+### 文本分类
+
+像任何模态的分类任务一样,文本分类将一段文本(可以是句子级别、段落或文档)从预定义的类别集合中进行标记。文本分类有许多实际应用,其中一些包括:
+
+* 情感分析:根据某些极性(如`积极`或`消极`)对文本进行标记,可以支持政治、金融和营销等领域的决策制定
+* 内容分类:根据某些主题对文本进行标记,有助于组织和过滤新闻和社交媒体提要中的信息(`天气`、`体育`、`金融`等)
+
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="sentiment-analysis")
+>>> preds = classifier("Hugging Face is the best thing since sliced bread!")
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.9991, 'label': 'POSITIVE'}]
+```
+
+### Token分类
+
+在任何NLP任务中,文本都经过预处理,将文本序列分成单个单词或子词。这些被称为[tokens](/glossary#token)。Token分类将每个`token`分配一个来自预定义类别集的标签。
+
+两种常见的Token分类是:
+
+* 命名实体识别(NER):根据实体类别(如组织、人员、位置或日期)对`token`进行标记。NER在生物医学设置中特别受欢迎,可以标记基因、蛋白质和药物名称。
+* 词性标注(POS):根据其词性(如名词、动词或形容词)对标记进行标记。POS对于帮助翻译系统了解两个相同的单词如何在语法上不同很有用(作为名词的银行与作为动词的银行)。
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="ner")
+>>> preds = classifier("Hugging Face is a French company based in New York City.")
+>>> preds = [
+... {
+... "entity": pred["entity"],
+... "score": round(pred["score"], 4),
+... "index": pred["index"],
+... "word": pred["word"],
+... "start": pred["start"],
+... "end": pred["end"],
+... }
+... for pred in preds
+... ]
+>>> print(*preds, sep="\n")
+{'entity': 'I-ORG', 'score': 0.9968, 'index': 1, 'word': 'Hu', 'start': 0, 'end': 2}
+{'entity': 'I-ORG', 'score': 0.9293, 'index': 2, 'word': '##gging', 'start': 2, 'end': 7}
+{'entity': 'I-ORG', 'score': 0.9763, 'index': 3, 'word': 'Face', 'start': 8, 'end': 12}
+{'entity': 'I-MISC', 'score': 0.9983, 'index': 6, 'word': 'French', 'start': 18, 'end': 24}
+{'entity': 'I-LOC', 'score': 0.999, 'index': 10, 'word': 'New', 'start': 42, 'end': 45}
+{'entity': 'I-LOC', 'score': 0.9987, 'index': 11, 'word': 'York', 'start': 46, 'end': 50}
+{'entity': 'I-LOC', 'score': 0.9992, 'index': 12, 'word': 'City', 'start': 51, 'end': 55}
+```
+
+### 问答
+
+问答是另一个`token-level`的任务,返回一个问题的答案,有时带有上下文(开放领域),有时不带上下文(封闭领域)。每当我们向虚拟助手提出问题时,例如询问一家餐厅是否营业,就会发生这种情况。它还可以提供客户或技术支持,并帮助搜索引擎检索您要求的相关信息。
+
+有两种常见的问答类型:
+
+* 提取式:给定一个问题和一些上下文,答案是从模型必须提取的上下文中的一段文本跨度。
+* 抽象式:给定一个问题和一些上下文,答案从上下文中生成;这种方法由[`Text2TextGenerationPipeline`]处理,而不是下面显示的[`QuestionAnsweringPipeline`]。
+
+
+```py
+>>> from transformers import pipeline
+
+>>> question_answerer = pipeline(task="question-answering")
+>>> preds = question_answerer(
+... question="What is the name of the repository?",
+... context="The name of the repository is huggingface/transformers",
+... )
+>>> print(
+... f"score: {round(preds['score'], 4)}, start: {preds['start']}, end: {preds['end']}, answer: {preds['answer']}"
+... )
+score: 0.9327, start: 30, end: 54, answer: huggingface/transformers
+```
+
+### 摘要
+
+摘要从较长的文本中创建一个较短的版本,同时尽可能保留原始文档的大部分含义。摘要是一个序列到序列的任务;它输出比输入更短的文本序列。有许多长篇文档可以进行摘要,以帮助读者快速了解主要要点。法案、法律和财务文件、专利和科学论文等文档可以摘要,以节省读者的时间并作为阅读辅助工具。
+
+像问答一样,摘要有两种类型:
+
+* 提取式:从原始文本中识别和提取最重要的句子
+* 抽象式:从原始文本生成目标摘要(可能包括不在输入文档中的新单词);[`SummarizationPipeline`]使用抽象方法。
+
+
+```py
+>>> from transformers import pipeline
+
+>>> summarizer = pipeline(task="summarization")
+>>> summarizer(
+... "In this work, we presented the Transformer, the first sequence transduction model based entirely on attention, replacing the recurrent layers most commonly used in encoder-decoder architectures with multi-headed self-attention. For translation tasks, the Transformer can be trained significantly faster than architectures based on recurrent or convolutional layers. On both WMT 2014 English-to-German and WMT 2014 English-to-French translation tasks, we achieve a new state of the art. In the former task our best model outperforms even all previously reported ensembles."
+... )
+[{'summary_text': ' The Transformer is the first sequence transduction model based entirely on attention . It replaces the recurrent layers most commonly used in encoder-decoder architectures with multi-headed self-attention . For translation tasks, the Transformer can be trained significantly faster than architectures based on recurrent or convolutional layers .'}]
+```
+
+### 翻译
+
+翻译将一种语言的文本序列转换为另一种语言。它对于帮助来自不同背景的人们相互交流、帮助翻译内容以吸引更广泛的受众,甚至成为学习工具以帮助人们学习一门新语言都非常重要。除了摘要之外,翻译也是一个序列到序列的任务,意味着模型接收输入序列并返回目标输出序列。
+
+在早期,翻译模型大多是单语的,但最近,越来越多的人对可以在多种语言之间进行翻译的多语言模型感兴趣。
+
+```py
+>>> from transformers import pipeline
+
+>>> text = "translate English to French: Hugging Face is a community-based open-source platform for machine learning."
+>>> translator = pipeline(task="translation", model="google-t5/t5-small")
+>>> translator(text)
+[{'translation_text': "Hugging Face est une tribune communautaire de l'apprentissage des machines."}]
+```
+
+### 语言模型
+
+语言模型是一种预测文本序列中单词的任务。它已成为一种非常流行的NLP任务,因为预训练的语言模型可以微调用于许多其他下游任务。最近,人们对大型语言模型(LLMs)表现出了极大的兴趣,这些模型展示了`zero learning`或`few-shot learning`的能力。这意味着模型可以解决它未被明确训练过的任务!语言模型可用于生成流畅和令人信服的文本,但需要小心,因为文本可能并不总是准确的。
+
+有两种类型的话语模型:
+
+* causal:模型的目标是预测序列中的下一个`token`,而未来的`tokens`被遮盖。
+
+ ```py
+ >>> from transformers import pipeline
+
+ >>> prompt = "Hugging Face is a community-based open-source platform for machine learning."
+ >>> generator = pipeline(task="text-generation")
+ >>> generator(prompt) # doctest: +SKIP
+ ```
+
+* masked:模型的目标是预测序列中被遮蔽的`token`,同时具有对序列中所有`tokens`的完全访问权限。
+
+ ```py
+ >>> text = "Hugging Face is a community-based open-source for machine learning."
+ >>> fill_mask = pipeline(task="fill-mask")
+ >>> preds = fill_mask(text, top_k=1)
+ >>> preds = [
+ ... {
+ ... "score": round(pred["score"], 4),
+ ... "token": pred["token"],
+ ... "token_str": pred["token_str"],
+ ... "sequence": pred["sequence"],
+ ... }
+ ... for pred in preds
+ ... ]
+ >>> preds
+ [{'score': 0.2236,
+ 'token': 1761,
+ 'token_str': ' platform',
+ 'sequence': 'Hugging Face is a community-based open-source platform for machine learning.'}]
+ ```
+
+## 多模态
+
+多模态任务要求模型处理多种数据模态(文本、图像、音频、视频)以解决特定问题。图像描述是一个多模态任务的例子,其中模型将图像作为输入并输出描述图像或图像某些属性的文本序列。
+
+虽然多模态模型处理不同的数据类型或模态,但内部预处理步骤帮助模型将所有数据类型转换为`embeddings`(向量或数字列表,包含有关数据的有意义信息)。对于像图像描述这样的任务,模型学习图像嵌入和文本嵌入之间的关系。
+
+### 文档问答
+
+文档问答是从文档中回答自然语言问题的任务。与`token-level`问答任务不同,文档问答将包含问题的文档的图像作为输入,并返回答案。文档问答可用于解析结构化文档并从中提取关键信息。在下面的例子中,可以从收据中提取总金额和找零金额。
+
+```py
+>>> from transformers import pipeline
+>>> from PIL import Image
+>>> import requests
+
+>>> url = "https://huggingface.co/datasets/hf-internal-testing/example-documents/resolve/main/jpeg_images/2.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> doc_question_answerer = pipeline("document-question-answering", model="magorshunov/layoutlm-invoices")
+>>> preds = doc_question_answerer(
+... question="What is the total amount?",
+... image=image,
+... )
+>>> preds
+[{'score': 0.8531, 'answer': '17,000', 'start': 4, 'end': 4}]
+```
+
+希望这个页面为您提供了一些有关每种模态中所有类型任务的背景信息以及每个任务的实际重要性。在[下一节](tasks_explained)中,您将了解Transformers如何解决这些任务。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/tasks/asr.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/tasks/asr.md
new file mode 100644
index 0000000000000000000000000000000000000000..a4fdbd308e4badc4d5a7ae13265a7c2a3784bc65
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/tasks/asr.md
@@ -0,0 +1,392 @@
+
+
+# 自动语音识别
+
+[[open-in-colab]]
+
+
+
+如果您想查看所有与本任务兼容的架构和检查点,最好查看[任务页](https://huggingface.co/tasks/automatic-speech-recognition)。
+
+
+
+在开始之前,请确保您已安装所有必要的库:
+
+```bash
+pip install transformers datasets evaluate jiwer
+```
+
+我们鼓励您登录自己的 Hugging Face 账户,这样您就可以上传并与社区分享您的模型。
+出现提示时,输入您的令牌登录:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## 加载 MInDS-14 数据集
+
+首先从🤗 Datasets 库中加载 [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14)
+数据集的一个较小子集。这将让您有机会先进行实验,确保一切正常,然后再花更多时间在完整数据集上进行训练。
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> minds = load_dataset("PolyAI/minds14", name="en-US", split="train[:100]")
+```
+
+使用 [`~Dataset.train_test_split`] 方法将数据集的 `train` 拆分为训练集和测试集:
+
+```py
+>>> minds = minds.train_test_split(test_size=0.2)
+```
+
+然后看看数据集:
+
+```py
+>>> minds
+DatasetDict({
+ train: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 16
+ })
+ test: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 4
+ })
+})
+```
+
+虽然数据集包含 `lang_id `和 `english_transcription` 等许多有用的信息,但在本指南中,
+您将专注于 `audio` 和 `transcription`。使用 [`~datasets.Dataset.remove_columns`] 方法删除其他列:
+
+```py
+>>> minds = minds.remove_columns(["english_transcription", "intent_class", "lang_id"])
+```
+
+再看看示例:
+
+```py
+>>> minds["train"][0]
+{'audio': {'array': array([-0.00024414, 0. , 0. , ..., 0.00024414,
+ 0.00024414, 0.00024414], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'sampling_rate': 8000},
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'transcription': "hi I'm trying to use the banking app on my phone and currently my checking and savings account balance is not refreshing"}
+```
+
+有 2 个字段:
+
+- `audio`:由语音信号形成的一维 `array`,用于加载和重新采样音频文件。
+- `transcription`:目标文本。
+
+## 预处理
+
+下一步是加载一个 Wav2Vec2 处理器来处理音频信号:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base")
+```
+
+MInDS-14 数据集的采样率为 8000kHz(您可以在其[数据集卡片](https://huggingface.co/datasets/PolyAI/minds14)中找到此信息),
+这意味着您需要将数据集重新采样为 16000kHz 以使用预训练的 Wav2Vec2 模型:
+
+```py
+>>> minds = minds.cast_column("audio", Audio(sampling_rate=16_000))
+>>> minds["train"][0]
+{'audio': {'array': array([-2.38064706e-04, -1.58618059e-04, -5.43987835e-06, ...,
+ 2.78103951e-04, 2.38446111e-04, 1.18740834e-04], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'sampling_rate': 16000},
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'transcription': "hi I'm trying to use the banking app on my phone and currently my checking and savings account balance is not refreshing"}
+```
+
+如您在上面的 `transcription` 中所看到的,文本包含大小写字符的混合。
+Wav2Vec2 分词器仅训练了大写字符,因此您需要确保文本与分词器的词汇表匹配:
+
+```py
+>>> def uppercase(example):
+... return {"transcription": example["transcription"].upper()}
+
+
+>>> minds = minds.map(uppercase)
+```
+
+现在创建一个预处理函数,该函数应该:
+
+1. 调用 `audio` 列以加载和重新采样音频文件。
+2. 从音频文件中提取 `input_values` 并使用处理器对 `transcription` 列执行 tokenizer 操作。
+
+```py
+>>> def prepare_dataset(batch):
+... audio = batch["audio"]
+... batch = processor(audio["array"], sampling_rate=audio["sampling_rate"], text=batch["transcription"])
+... batch["input_length"] = len(batch["input_values"][0])
+... return batch
+```
+
+要在整个数据集上应用预处理函数,可以使用🤗 Datasets 的 [`~datasets.Dataset.map`] 函数。
+您可以通过增加 `num_proc` 参数来加速 `map` 的处理进程数量。
+使用 [`~datasets.Dataset.remove_columns`] 方法删除不需要的列:
+
+```py
+>>> encoded_minds = minds.map(prepare_dataset, remove_columns=minds.column_names["train"], num_proc=4)
+```
+
+🤗 Transformers 没有用于 ASR 的数据整理器,因此您需要调整 [`DataCollatorWithPadding`] 来创建一个示例批次。
+它还会动态地将您的文本和标签填充到其批次中最长元素的长度(而不是整个数据集),以使它们具有统一的长度。
+虽然可以通过在 `tokenizer` 函数中设置 `padding=True` 来填充文本,但动态填充更有效。
+
+与其他数据整理器不同,这个特定的数据整理器需要对 `input_values` 和 `labels `应用不同的填充方法:
+
+```py
+>>> import torch
+
+>>> from dataclasses import dataclass, field
+>>> from typing import Any, Dict, List, Optional, Union
+
+
+>>> @dataclass
+... class DataCollatorCTCWithPadding:
+... processor: AutoProcessor
+... padding: Union[bool, str] = "longest"
+
+... def __call__(self, features: List[Dict[str, Union[List[int], torch.Tensor]]]) -> Dict[str, torch.Tensor]:
+... # split inputs and labels since they have to be of different lengths and need
+... # different padding methods
+... input_features = [{"input_values": feature["input_values"][0]} for feature in features]
+... label_features = [{"input_ids": feature["labels"]} for feature in features]
+
+... batch = self.processor.pad(input_features, padding=self.padding, return_tensors="pt")
+
+... labels_batch = self.processor.pad(labels=label_features, padding=self.padding, return_tensors="pt")
+
+... # replace padding with -100 to ignore loss correctly
+... labels = labels_batch["input_ids"].masked_fill(labels_batch.attention_mask.ne(1), -100)
+
+... batch["labels"] = labels
+
+... return batch
+```
+
+现在实例化您的 `DataCollatorForCTCWithPadding`:
+
+```py
+>>> data_collator = DataCollatorCTCWithPadding(processor=processor, padding="longest")
+```
+
+## 评估
+
+在训练过程中包含一个指标通常有助于评估模型的性能。
+您可以通过🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 库快速加载一个评估方法。
+对于这个任务,加载 [word error rate](https://huggingface.co/spaces/evaluate-metric/wer)(WER)指标
+(请参阅🤗 Evaluate [快速上手](https://huggingface.co/docs/evaluate/a_quick_tour)以了解如何加载和计算指标):
+
+```py
+>>> import evaluate
+
+>>> wer = evaluate.load("wer")
+```
+
+然后创建一个函数,将您的预测和标签传递给 [`~evaluate.EvaluationModule.compute`] 来计算 WER:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(pred):
+... pred_logits = pred.predictions
+... pred_ids = np.argmax(pred_logits, axis=-1)
+
+... pred.label_ids[pred.label_ids == -100] = processor.tokenizer.pad_token_id
+
+... pred_str = processor.batch_decode(pred_ids)
+... label_str = processor.batch_decode(pred.label_ids, group_tokens=False)
+
+... wer = wer.compute(predictions=pred_str, references=label_str)
+
+... return {"wer": wer}
+```
+
+您的 `compute_metrics` 函数现在已经准备就绪,当您设置好训练时将返回给此函数。
+
+## 训练
+
+
+
+
+
+如果您不熟悉使用[`Trainer`]微调模型,请查看这里的基本教程[here](../training#train-with-pytorch-trainer)!
+
+
+
+现在您已经准备好开始训练您的模型了!使用 [`AutoModelForCTC`] 加载 Wav2Vec2。
+使用 `ctc_loss_reduction` 参数指定要应用的减少方式。通常最好使用平均值而不是默认的求和:
+
+```py
+>>> from transformers import AutoModelForCTC, TrainingArguments, Trainer
+
+>>> model = AutoModelForCTC.from_pretrained(
+... "facebook/wav2vec2-base",
+... ctc_loss_reduction="mean",
+... pad_token_id=processor.tokenizer.pad_token_id,
+)
+```
+
+此时,只剩下 3 个步骤:
+
+1. 在 [`TrainingArguments`] 中定义您的训练参数。唯一必需的参数是 `output_dir`,用于指定保存模型的位置。
+ 您可以通过设置 `push_to_hub=True` 将此模型推送到 Hub(您需要登录到 Hugging Face 才能上传您的模型)。
+ 在每个 epoch 结束时,[`Trainer`] 将评估 WER 并保存训练检查点。
+2. 将训练参数与模型、数据集、分词器、数据整理器和 `compute_metrics` 函数一起传递给 [`Trainer`]。
+3. 调用 [`~Trainer.train`] 来微调您的模型。
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_asr_mind_model",
+... per_device_train_batch_size=8,
+... gradient_accumulation_steps=2,
+... learning_rate=1e-5,
+... warmup_steps=500,
+... max_steps=2000,
+... gradient_checkpointing=True,
+... fp16=True,
+... group_by_length=True,
+... eval_strategy="steps",
+... per_device_eval_batch_size=8,
+... save_steps=1000,
+... eval_steps=1000,
+... logging_steps=25,
+... load_best_model_at_end=True,
+... metric_for_best_model="wer",
+... greater_is_better=False,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=encoded_minds["train"],
+... eval_dataset=encoded_minds["test"],
+... processing_class=processor,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+训练完成后,使用 [`~transformers.Trainer.push_to_hub`] 方法将您的模型分享到 Hub,方便大家使用您的模型:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+要深入了解如何微调模型进行自动语音识别,
+请查看这篇博客[文章](https://huggingface.co/blog/fine-tune-wav2vec2-english)以了解英语 ASR,
+还可以参阅[这篇文章](https://huggingface.co/blog/fine-tune-xlsr-wav2vec2)以了解多语言 ASR。
+
+
+
+## 推断
+
+很好,现在您已经微调了一个模型,您可以用它进行推断了!
+
+加载您想要运行推断的音频文件。请记住,如果需要,将音频文件的采样率重新采样为与模型匹配的采样率!
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", "en-US", split="train")
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
+>>> sampling_rate = dataset.features["audio"].sampling_rate
+>>> audio_file = dataset[0]["audio"]["path"]
+```
+
+尝试使用微调后的模型进行推断的最简单方法是使用 [`pipeline`]。
+使用您的模型实例化一个用于自动语音识别的 `pipeline`,并将您的音频文件传递给它:
+
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline("automatic-speech-recognition", model="stevhliu/my_awesome_asr_minds_model")
+>>> transcriber(audio_file)
+{'text': 'I WOUD LIKE O SET UP JOINT ACOUNT WTH Y PARTNER'}
+```
+
+
+
+转录结果还不错,但可以更好!尝试用更多示例微调您的模型,以获得更好的结果!
+
+
+
+如果您愿意,您也可以手动复制 `pipeline` 的结果:
+
+
+
+
+加载一个处理器来预处理音频文件和转录,并将 `input` 返回为 PyTorch 张量:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("stevhliu/my_awesome_asr_mind_model")
+>>> inputs = processor(dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
+```
+
+将您的输入传递给模型并返回 logits:
+
+```py
+>>> from transformers import AutoModelForCTC
+
+>>> model = AutoModelForCTC.from_pretrained("stevhliu/my_awesome_asr_mind_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+获取具有最高概率的预测 `input_ids`,并使用处理器将预测的 `input_ids` 解码回文本:
+
+```py
+>>> import torch
+
+>>> predicted_ids = torch.argmax(logits, dim=-1)
+>>> transcription = processor.batch_decode(predicted_ids)
+>>> transcription
+['I WOUL LIKE O SET UP JOINT ACOUNT WTH Y PARTNER']
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/tf_xla.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/tf_xla.md
new file mode 100644
index 0000000000000000000000000000000000000000..2e5b444d876c0a72ae91fe044a77455c2c3e59dc
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/tf_xla.md
@@ -0,0 +1,179 @@
+
+
+# 用于 TensorFlow 模型的 XLA 集成
+
+[[open-in-colab]]
+
+加速线性代数,也称为XLA,是一个用于加速TensorFlow模型运行时间的编译器。从[官方文档](https://www.tensorflow.org/xla)中可以看到:
+
+XLA(加速线性代数)是一种针对线性代数的特定领域编译器,可以在可能不需要更改源代码的情况下加速TensorFlow模型。
+
+在TensorFlow中使用XLA非常简单——它包含在`tensorflow`库中,并且可以使用任何图创建函数中的`jit_compile`参数来触发,例如[`tf.function`](https://www.tensorflow.org/guide/intro_to_graphs)。在使用Keras方法如`fit()`和`predict()`时,只需将`jit_compile`参数传递给`model.compile()`即可启用XLA。然而,XLA不仅限于这些方法 - 它还可以用于加速任何任意的`tf.function`。
+
+在🤗 Transformers中,几个TensorFlow方法已经被重写为与XLA兼容,包括[GPT2](https://huggingface.co/docs/transformers/model_doc/gpt2)、[T5](https://huggingface.co/docs/transformers/model_doc/t5)和[OPT](https://huggingface.co/docs/transformers/model_doc/opt)等文本生成模型,以及[Whisper](https://huggingface.co/docs/transformers/model_doc/whisper)等语音处理模型。
+
+虽然确切的加速倍数很大程度上取决于模型,但对于🤗 Transformers中的TensorFlow文本生成模型,我们注意到速度提高了约100倍。本文档将解释如何在这些模型上使用XLA获得最大的性能。如果您有兴趣了解更多关于基准测试和我们在XLA集成背后的设计哲学的信息,我们还将提供额外的资源链接。
+
+
+## 使用 XLA 运行 TensorFlow 函数
+
+让我们考虑以下TensorFlow 中的模型:
+
+```py
+import tensorflow as tf
+
+model = tf.keras.Sequential(
+ [tf.keras.layers.Dense(10, input_shape=(10,), activation="relu"), tf.keras.layers.Dense(5, activation="softmax")]
+)
+```
+
+上述模型接受维度为 `(10,)` 的输入。我们可以像下面这样使用模型进行前向传播:
+
+```py
+# Generate random inputs for the model.
+batch_size = 16
+input_vector_dim = 10
+random_inputs = tf.random.normal((batch_size, input_vector_dim))
+
+# Run a forward pass.
+_ = model(random_inputs)
+```
+
+为了使用 XLA 编译的函数运行前向传播,我们需要执行以下操作:
+
+```py
+xla_fn = tf.function(model, jit_compile=True)
+_ = xla_fn(random_inputs)
+```
+
+`model`的默认`call()`函数用于编译XLA图。但如果你想将其他模型函数编译成XLA,也是可以的,如下所示:
+
+```py
+my_xla_fn = tf.function(model.my_xla_fn, jit_compile=True)
+```
+
+## 在🤗 Transformers库中使用XLA运行TensorFlow文本生成模型
+
+要在🤗 Transformers中启用XLA加速生成,您需要安装最新版本的`transformers`。您可以通过运行以下命令来安装它:
+
+```bash
+pip install transformers --upgrade
+```
+
+然后您可以运行以下代码:
+
+```py
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+# Will error if the minimal version of Transformers is not installed.
+from transformers.utils import check_min_version
+
+check_min_version("4.21.0")
+
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+input_string = ["TensorFlow is"]
+
+# One line to create an XLA generation function
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+tokenized_input = tokenizer(input_string, return_tensors="tf")
+generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+
+decoded_text = tokenizer.decode(generated_tokens[0], skip_special_tokens=True)
+print(f"Generated -- {decoded_text}")
+# Generated -- TensorFlow is an open-source, open-source, distributed-source application # framework for the
+```
+
+正如您所注意到的,在`generate()`上启用XLA只需要一行代码。其余部分代码保持不变。然而,上面的代码片段中有一些与XLA相关的注意事项。您需要了解这些注意事项,以充分利用XLA可能带来的性能提升。我们将在下面的部分讨论这些内容。
+
+## 需要关注的注意事项
+
+当您首次执行启用XLA的函数(如上面的`xla_generate()`)时,它将在内部尝试推断计算图,这是一个耗时的过程。这个过程被称为[“tracing”](https://www.tensorflow.org/guide/intro_to_graphs#when_is_a_function_tracing)。
+
+您可能会注意到生成时间并不快。连续调用`xla_generate()`(或任何其他启用了XLA的函数)不需要再次推断计算图,只要函数的输入与最初构建计算图时的形状相匹配。对于具有固定输入形状的模态(例如图像),这不是问题,但如果您正在处理具有可变输入形状的模态(例如文本),则必须注意。
+
+为了确保`xla_generate()`始终使用相同的输入形状,您可以在调用`tokenizer`时指定`padding`参数。
+
+```py
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+input_string = ["TensorFlow is"]
+
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+# Here, we call the tokenizer with padding options.
+tokenized_input = tokenizer(input_string, pad_to_multiple_of=8, padding=True, return_tensors="tf")
+
+generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+decoded_text = tokenizer.decode(generated_tokens[0], skip_special_tokens=True)
+print(f"Generated -- {decoded_text}")
+```
+
+通过这种方式,您可以确保`xla_generate()`的输入始终具有它跟踪的形状,从而加速生成时间。您可以使用以下代码来验证这一点:
+
+```py
+import time
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+for input_string in ["TensorFlow is", "TensorFlow is a", "TFLite is a"]:
+ tokenized_input = tokenizer(input_string, pad_to_multiple_of=8, padding=True, return_tensors="tf")
+ start = time.time_ns()
+ generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+ end = time.time_ns()
+ print(f"Execution time -- {(end - start) / 1e6:.1f} ms\n")
+```
+
+在Tesla T4 GPU上,您可以期望如下的输出:
+
+```bash
+Execution time -- 30819.6 ms
+
+Execution time -- 79.0 ms
+
+Execution time -- 78.9 ms
+```
+
+第一次调用`xla_generate()`会因为`tracing`而耗时,但后续的调用会快得多。请注意,任何时候对生成选项的更改都会触发重新`tracing`,从而导致生成时间减慢。
+
+在本文档中,我们没有涵盖🤗 Transformers提供的所有文本生成选项。我们鼓励您阅读文档以了解高级用例。
+
+## 附加资源
+
+以下是一些附加资源,如果您想深入了解在🤗 Transformers和其他库下使用XLA:
+
+* [这个Colab Notebook](https://colab.research.google.com/github/huggingface/blog/blob/main/notebooks/91_tf_xla_generate.ipynb) 提供了一个互动演示,让您可以尝试使用XLA兼容的编码器-解码器(例如[T5](https://huggingface.co/docs/transformers/model_doc/t5))和仅解码器(例如[GPT2](https://huggingface.co/docs/transformers/model_doc/gpt2))文本生成模型。
+
+* [这篇博客文章](https://huggingface.co/blog/tf-xla-generate) 提供了XLA兼容模型的比较基准概述,以及关于在TensorFlow中使用XLA的友好介绍。
+
+* [这篇博客文章](https://blog.tensorflow.org/2022/11/how-hugging-face-improved-text-generation-performance-with-xla.html) 讨论了我们在🤗 Transformers中为TensorFlow模型添加XLA支持的设计理念。
+
+* 推荐用于更多学习XLA和TensorFlow图的资源:
+ * [XLA:面向机器学习的优化编译器](https://www.tensorflow.org/xla)
+ * [图和tf.function简介](https://www.tensorflow.org/guide/intro_to_graphs)
+ * [使用tf.function获得更好的性能](https://www.tensorflow.org/guide/function)
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/tflite.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/tflite.md
new file mode 100644
index 0000000000000000000000000000000000000000..f0280156def4313023993a72b3c3b6081a8bd400
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/tflite.md
@@ -0,0 +1,54 @@
+
+
+# 导出为 TFLite
+
+[TensorFlow Lite](https://www.tensorflow.org/lite/guide) 是一个轻量级框架,用于资源受限的设备上,如手机、嵌入式系统和物联网(IoT)设备,部署机器学习模型。TFLite 旨在在计算能力、内存和功耗有限的设备上优化和高效运行模型。模型以一种特殊的高效可移植格式表示,其文件扩展名为 `.tflite`。
+
+🤗 Optimum 通过 `exporters.tflite` 模块提供将 🤗 Transformers 模型导出至 TFLite 格式的功能。请参考 [🤗 Optimum 文档](https://huggingface.co/docs/optimum/exporters/tflite/overview) 以获取支持的模型架构列表。
+
+要将模型导出为 TFLite 格式,请安装所需的依赖项:
+
+```bash
+pip install optimum[exporters-tf]
+```
+
+请参阅 [🤗 Optimum 文档](https://huggingface.co/docs/optimum/main/en/exporters/tflite/usage_guides/export_a_model) 以查看所有可用参数,或者在命令行中查看帮助:
+
+```bash
+optimum-cli export tflite --help
+```
+
+运行以下命令,以从 🤗 Hub 导出模型的检查点(checkpoint),以 `google-bert/bert-base-uncased` 为例:
+
+```bash
+optimum-cli export tflite --model google-bert/bert-base-uncased --sequence_length 128 bert_tflite/
+```
+
+你应该能在日志中看到导出进度以及生成的 `model.tflite` 文件的保存位置,如下所示:
+
+```bash
+Validating TFLite model...
+ -[✓] TFLite model output names match reference model (logits)
+ - Validating TFLite Model output "logits":
+ -[✓] (1, 128, 30522) matches (1, 128, 30522)
+ -[x] values not close enough, max diff: 5.817413330078125e-05 (atol: 1e-05)
+The TensorFlow Lite export succeeded with the warning: The maximum absolute difference between the output of the reference model and the TFLite exported model is not within the set tolerance 1e-05:
+- logits: max diff = 5.817413330078125e-05.
+ The exported model was saved at: bert_tflite
+```
+
+上面的示例说明了从 🤗 Hub 导出检查点的过程。导出本地模型时,首先需要确保将模型的权重和分词器文件保存在同一目录(`local_path`)中。在使用 CLI(命令行)时,将 `local_path` 传递给 `model` 参数,而不是 🤗 Hub 上的检查点名称。
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/tiktoken.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/tiktoken.md
new file mode 100644
index 0000000000000000000000000000000000000000..c8ef6b129eccc0001b8b74b15ffee2f80d48e451
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/tiktoken.md
@@ -0,0 +1,55 @@
+
+
+# Transformers与Tiktonken的互操作性
+
+在🤗 transformers中,当使用`from_pretrained`方法从Hub加载模型时,如果模型包含tiktoken格式的`tokenizer.model`文件,框架可以无缝支持tiktoken模型文件,并自动将其转换为我们的[快速词符化器](https://huggingface.co/docs/transformers/main/en/main_classes/tokenizer#transformers.PreTrainedTokenizerFast)。
+
+### 已知包含`tiktoken.model`文件发布的模型:
+ - gpt2
+ - llama3
+
+## 使用示例
+
+为了在transformers中正确加载`tiktoken`文件,请确保`tiktoken.model`文件是tiktoken格式的,并且会在加载`from_pretrained`时自动加载。以下展示如何从同一个文件中加载词符化器(tokenizer)和模型:
+
+```py
+from transformers import AutoTokenizer
+
+model_id = "meta-llama/Meta-Llama-3-8B-Instruct"
+tokenizer = AutoTokenizer.from_pretrained(model_id, subfolder="original")
+```
+## 创建tiktoken词符化器(tokenizer)
+
+`tokenizer.model`文件中不包含任何额外的词符(token)或模式字符串(pattern strings)的信息。如果这些信息很重要,需要将词符化器(tokenizer)转换为适用于[`PreTrainedTokenizerFast`]类的`tokenizer.json`格式。
+
+使用[tiktoken.get_encoding](https://github.com/openai/tiktoken/blob/63527649963def8c759b0f91f2eb69a40934e468/tiktoken/registry.py#L63)生成`tokenizer.model`文件,再使用[`convert_tiktoken_to_fast`]函数将其转换为`tokenizer.json`文件。
+
+```py
+
+from transformers.integrations.tiktoken import convert_tiktoken_to_fast
+from tiktoken import get_encoding
+
+# You can load your custom encoding or the one provided by OpenAI
+encoding = get_encoding("gpt2")
+convert_tiktoken_to_fast(encoding, "config/save/dir")
+```
+
+生成的`tokenizer.json`文件将被保存到指定的目录,并且可以通过[`PreTrainedTokenizerFast`]类来加载。
+
+```py
+tokenizer = PreTrainedTokenizerFast.from_pretrained("config/save/dir")
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/tokenizer_summary.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/tokenizer_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..c349154f961218317721a1764bd285755b53e50a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/tokenizer_summary.md
@@ -0,0 +1,234 @@
+
+
+# 分词器的摘要
+[[open-in-colab]]
+
+在这个页面,我们来仔细研究分词的知识。
+", "ug"]`,因为符号`"m"`不在基础词典内。
+通常来看的话,单个字母像`"m"`不会被`""`符号替换掉,因为训练数据通常包括了每个字母,每个字母至少出现了一次,但是在特殊的符号
+中也可能发生像emojis。
+
+就像之前提到的那样,词典的大小,举个例子,基础词典的大小 + 融合的数量,是一个需要配置的超参数。举个例子:[GPT](model_doc/gpt)
+的词典大小是40,478,因为GPT有着478个基础词典内的字符,在40,000次融合以后选择了停止训练。
+
+#### Byte-level BPE
+
+一个包含了所有可能的基础字符的基础字典可能会非常大,如果考虑将所有的unicode字符作为基础字符。为了拥有一个更好的基础词典,[GPT-2](https://cdn.openai.com/better-language-models/language_models_are_unsupervised_multitask_learners.pdf)使用了字节
+作为基础词典,这是一个非常聪明的技巧,迫使基础词典是256大小,而且确保了所有基础字符包含在这个词典内。使用了其他的规则
+来处理标点符号,这个GPT2的分词器能对每个文本进行分词,不需要使用到符号。[GPT-2](model_doc/gpt)有一个大小是50,257
+的词典,对应到256字节的基础tokens,一个特殊的文本结束token,这些符号经过了50,000次融合学习。
+
+
+
+这是开始使用 TorchScript 进行实验的起点,我们仍在探索其在变量输入大小模型中的能力。
+这是我们关注的焦点,我们将在即将发布的版本中深入分析,提供更多的代码示例、更灵活的实现以及比较
+Python 代码与编译 TorchScript 的性能基准。
+
+
+
+根据 [TorchScript 文档](https://pytorch.org/docs/stable/jit.html):
+
+> TorchScript 是从 PyTorch 代码创建可序列化和可优化的模型的一种方式。
+
+有两个 PyTorch 模块:[JIT 和 TRACE](https://pytorch.org/docs/stable/jit.html)。
+这两个模块允许开发人员将其模型导出到其他程序中重用,比如面向效率的 C++ 程序。
+
+我们提供了一个接口,允许您将 🤗 Transformers 模型导出为 TorchScript,
+以便在与基于 PyTorch 的 Python 程序不同的环境中重用。
+本文解释如何使用 TorchScript 导出并使用我们的模型。
+
+导出模型需要两个步骤:
+
+- 使用 `torchscript` 参数实例化模型
+- 使用虚拟输入进行前向传递
+
+这些必要条件意味着开发人员应该注意以下详细信息。
+
+## TorchScript 参数和绑定权重
+
+`torchscript` 参数是必需的,因为大多数 🤗 Transformers 语言模型的 `Embedding` 层和
+`Decoding` 层之间有绑定权重。TorchScript 不允许导出具有绑定权重的模型,因此必须事先解绑和克隆权重。
+
+使用 `torchscript` 参数实例化的模型将其 `Embedding` 层和 `Decoding` 层分开,
+这意味着它们不应该在后续进行训练。训练将导致这两层不同步,产生意外结果。
+
+对于没有语言模型头部的模型,情况不同,因为这些模型没有绑定权重。
+这些模型可以安全地导出而无需 `torchscript` 参数。
+
+## 虚拟输入和标准长度
+
+虚拟输入用于模型的前向传递。当输入的值传播到各层时,PyTorch 会跟踪在每个张量上执行的不同操作。
+然后使用记录的操作来创建模型的 *trace* 。
+
+跟踪是相对于输入的维度创建的。因此,它受到虚拟输入的维度限制,对于任何其他序列长度或批量大小都不起作用。
+当尝试使用不同大小时,会引发以下错误:
+
+```text
+`The expanded size of the tensor (3) must match the existing size (7) at non-singleton dimension 2`
+```
+
+我们建议使用至少与推断期间将馈送到模型的最大输入一样大的虚拟输入大小进行跟踪。
+填充可以帮助填补缺失的值。然而,由于模型是使用更大的输入大小进行跟踪的,矩阵的维度也会很大,导致更多的计算。
+
+在每个输入上执行的操作总数要仔细考虑,并在导出不同序列长度模型时密切关注性能。
+
+## 在 Python 中使用 TorchScript
+
+本节演示了如何保存和加载模型以及如何使用 trace 进行推断。
+
+### 保存模型
+
+要使用 TorchScript 导出 `BertModel`,请从 `BertConfig` 类实例化 `BertModel`,
+然后将其保存到名为 `traced_bert.pt` 的磁盘文件中:
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+
+enc = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+
+# 对输入文本分词
+text = "[CLS] Who was Jim Henson ? [SEP] Jim Henson was a puppeteer [SEP]"
+tokenized_text = enc.tokenize(text)
+
+# 屏蔽一个输入 token
+masked_index = 8
+tokenized_text[masked_index] = "[MASK]"
+indexed_tokens = enc.convert_tokens_to_ids(tokenized_text)
+segments_ids = [0, 0, 0, 0, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1]
+
+# 创建虚拟输入
+tokens_tensor = torch.tensor([indexed_tokens])
+segments_tensors = torch.tensor([segments_ids])
+dummy_input = [tokens_tensor, segments_tensors]
+
+# 使用 torchscript 参数初始化模型
+# 即使此模型没有 LM Head,也将参数设置为 True。
+config = BertConfig(
+ vocab_size_or_config_json_file=32000,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ torchscript=True,
+)
+
+# 实例化模型
+model = BertModel(config)
+
+# 模型需要处于评估模式
+model.eval()
+
+# 如果您使用 *from_pretrained* 实例化模型,还可以轻松设置 TorchScript 参数
+model = BertModel.from_pretrained("google-bert/bert-base-uncased", torchscript=True)
+
+# 创建 trace
+traced_model = torch.jit.trace(model, [tokens_tensor, segments_tensors])
+torch.jit.save(traced_model, "traced_bert.pt")
+```
+
+### 加载模型
+
+现在,您可以从磁盘加载先前保存的 `BertModel`、`traced_bert.pt`,并在先前初始化的 `dummy_input` 上使用:
+
+```python
+loaded_model = torch.jit.load("traced_bert.pt")
+loaded_model.eval()
+
+all_encoder_layers, pooled_output = loaded_model(*dummy_input)
+```
+
+### 使用 trace 模型进行推断
+
+通过使用其 `__call__` dunder 方法使用 trace 模型进行推断:
+
+```python
+traced_model(tokens_tensor, segments_tensors)
+```
+
+## 使用 Neuron SDK 将 Hugging Face TorchScript 模型部署到 AWS
+
+AWS 引入了用于云端低成本、高性能机器学习推理的
+[Amazon EC2 Inf1](https://aws.amazon.com/ec2/instance-types/inf1/) 实例系列。
+Inf1 实例由 AWS Inferentia 芯片提供支持,这是一款专为深度学习推理工作负载而构建的定制硬件加速器。
+[AWS Neuron](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/#) 是
+Inferentia 的 SDK,支持对 transformers 模型进行跟踪和优化,以便在 Inf1 上部署。Neuron SDK 提供:
+
+1. 简单易用的 API,只需更改一行代码即可为云端推理跟踪和优化 TorchScript 模型。
+2. 针对[改进的性能成本](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/benchmark/)的即插即用性能优化。
+3. 支持使用 [PyTorch](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/bert_tutorial/tutorial_pretrained_bert.html)
+ 或 [TensorFlow](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/tensorflow/huggingface_bert/huggingface_bert.html)
+ 构建的 Hugging Face transformers 模型。
+
+### 影响
+
+基于 [BERT(来自 Transformers 的双向编码器表示)](https://huggingface.co/docs/transformers/main/model_doc/bert)架构的
+transformers 模型,或其变体,如 [distilBERT](https://huggingface.co/docs/transformers/main/model_doc/distilbert)
+和 [roBERTa](https://huggingface.co/docs/transformers/main/model_doc/roberta) 在 Inf1 上运行最佳,
+可用于生成抽取式问答、序列分类和标记分类等任务。然而,文本生成任务仍可以适应在 Inf1 上运行,
+如这篇 [AWS Neuron MarianMT 教程](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/transformers-marianmt.html)所述。
+有关可以直接在 Inferentia 上转换的模型的更多信息,请参阅 Neuron 文档的[模型架构适配](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/models/models-inferentia.html#models-inferentia)章节。
+
+### 依赖关系
+
+使用 AWS Neuron 将模型转换为模型需要一个
+[Neuron SDK 环境](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/neuron-frameworks/pytorch-neuron/index.html#installation-guide),
+它已经预先配置在 [AWS 深度学习 AMI](https://docs.aws.amazon.com/dlami/latest/devguide/tutorial-inferentia-launching.html)上。
+
+### 将模型转换为 AWS Neuron
+
+使用与 [Python 中使用 TorchScript](torchscript#using-torchscript-in-python) 相同的代码来跟踪
+`BertModel` 以将模型转换为 AWS NEURON。导入 `torch.neuron` 框架扩展以通过 Python API 访问 Neuron SDK 的组件:
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+import torch.neuron
+```
+
+您只需要修改下面这一行:
+
+```diff
+- torch.jit.trace(model, [tokens_tensor, segments_tensors])
++ torch.neuron.trace(model, [token_tensor, segments_tensors])
+```
+
+这样就能使 Neuron SDK 跟踪模型并对其进行优化,以在 Inf1 实例上运行。
+
+要了解有关 AWS Neuron SDK 功能、工具、示例教程和最新更新的更多信息,
+请参阅 [AWS NeuronSDK 文档](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/index.html)。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/training.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/training.md
new file mode 100644
index 0000000000000000000000000000000000000000..aeacf732c22f421f31cbf5295b51f1d544ec199a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/zh/training.md
@@ -0,0 +1,407 @@
+
+
+# 微调预训练模型
+
+[[open-in-colab]]
+
+使用预训练模型有许多显著的好处。它降低了计算成本,减少了碳排放,同时允许您使用最先进的模型,而无需从头开始训练一个。🤗 Transformers 提供了涉及各种任务的成千上万的预训练模型。当您使用预训练模型时,您需要在与任务相关的数据集上训练该模型。这种操作被称为微调,是一种非常强大的训练技术。在本教程中,您将使用您选择的深度学习框架来微调一个预训练模型:
+
+* 使用 🤗 Transformers 的 [`Trainer`] 来微调预训练模型。
+* 在 TensorFlow 中使用 Keras 来微调预训练模型。
+* 在原生 PyTorch 中微调预训练模型。
+
+
+
+
+
+您将会看到一个警告,提到一些预训练权重未被使用,以及一些权重被随机初始化。不用担心,这是完全正常的!BERT 模型的预训练`head`被丢弃,并替换为一个随机初始化的分类`head`。您将在您的序列分类任务上微调这个新模型`head`,将预训练模型的知识转移给它。
+
+
+
+### 训练超参数
+
+接下来,创建一个 [`TrainingArguments`] 类,其中包含您可以调整的所有超参数以及用于激活不同训练选项的标志。对于本教程,您可以从默认的训练[超参数](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments)开始,但随时可以尝试不同的设置以找到最佳设置。
+
+指定保存训练检查点的位置:
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(output_dir="test_trainer")
+```
+
+### 评估
+
+[`Trainer`] 在训练过程中不会自动评估模型性能。您需要向 [`Trainer`] 传递一个函数来计算和展示指标。[🤗 Evaluate](https://huggingface.co/docs/evaluate/index) 库提供了一个简单的 [`accuracy`](https://huggingface.co/spaces/evaluate-metric/accuracy) 函数,您可以使用 [`evaluate.load`] 函数加载它(有关更多信息,请参阅此[快速入门](https://huggingface.co/docs/evaluate/a_quick_tour)):
+
+```py
+>>> import numpy as np
+>>> import evaluate
+
+>>> metric = evaluate.load("accuracy")
+```
+在 `metric` 上调用 [`~evaluate.compute`] 来计算您的预测的准确性。在将预测传递给 `compute` 之前,您需要将预测转换为`logits`(请记住,所有 🤗 Transformers 模型都返回对`logits`):
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... predictions = np.argmax(logits, axis=-1)
+... return metric.compute(predictions=predictions, references=labels)
+```
+
+如果您希望在微调过程中监视评估指标,请在您的训练参数中指定 `eval_strategy` 参数,以在每个`epoch`结束时展示评估指标:
+
+```py
+>>> from transformers import TrainingArguments, Trainer
+
+>>> training_args = TrainingArguments(output_dir="test_trainer", eval_strategy="epoch")
+```
+
+### 训练器
+
+创建一个包含您的模型、训练参数、训练和测试数据集以及评估函数的 [`Trainer`] 对象:
+
+
+```py
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=small_train_dataset,
+... eval_dataset=small_eval_dataset,
+... compute_metrics=compute_metrics,
+... )
+```
+然后调用[`~transformers.Trainer.train`]以微调模型:
+
+```py
+>>> trainer.train()
+```
+
+
+
+
+当您使用 `compile()` 编译模型时,无需传递损失参数!如果不指定损失参数,Hugging Face 模型会自动选择适合其任务和模型架构的损失函数。如果需要,您始终可以自己指定损失函数以覆盖默认配置。
+
+
+
+这种方法对于较小的数据集效果很好,但对于较大的数据集,您可能会发现它开始变得有问题。为什么呢?因为分词后的数组和标签必须完全加载到内存中,而且由于 NumPy 无法处理“不规则”数组,因此每个分词后的样本长度都必须被填充到数据集中最长样本的长度。这将使您的数组变得更大,而所有这些`padding tokens`也会减慢训练速度!
+
+
+### 将数据加载为 tf.data.Dataset
+
+如果您想避免训练速度减慢,可以将数据加载为 `tf.data.Dataset`。虽然您可以自己编写自己的 `tf.data` 流水线,但我们有两种方便的方法来实现这一点:
+
+- [`~TFPreTrainedModel.prepare_tf_dataset`]:这是我们在大多数情况下推荐的方法。因为它是模型上的一个方法,它可以检查模型以自动确定哪些列可用作模型输入,并丢弃其他列以创建一个更简单、性能更好的数据集。
+- [`~datasets.Dataset.to_tf_dataset`]:这个方法更低级,但当您希望完全控制数据集的创建方式时非常有用,可以通过指定要包括的确切 `columns` 和 `label_cols` 来实现。
+
+在使用 [`~TFPreTrainedModel.prepare_tf_dataset`] 之前,您需要将`tokenizer`的输出添加到数据集作为列,如下面的代码示例所示:
+
+```py
+def tokenize_dataset(data):
+ # Keys of the returned dictionary will be added to the dataset as columns
+ return tokenizer(data["text"])
+
+
+dataset = dataset.map(tokenize_dataset)
+```
+请记住,默认情况下,Hugging Face 数据集存储在硬盘上,因此这不会增加您的内存使用!一旦列已经添加,您可以从数据集中流式的传输批次数据,并为每个批次添加`padding tokens`,这与为整个数据集添加`padding tokens`相比,大大减少了`padding tokens`的数量。
+
+```py
+>>> tf_dataset = model.prepare_tf_dataset(dataset["train"], batch_size=16, shuffle=True, tokenizer=tokenizer)
+```
+请注意,在上面的代码示例中,您需要将`tokenizer`传递给`prepare_tf_dataset`,以便它可以在加载批次时正确填充它们。如果数据集中的所有样本都具有相同的长度而且不需要填充,您可以跳过此参数。如果需要执行比填充样本更复杂的操作(例如,用于掩码语言模型的`tokens` 替换),则可以使用 `collate_fn` 参数,而不是传递一个函数来将样本列表转换为批次并应用任何所需的预处理。请查看我们的[示例](https://github.com/huggingface/transformers/tree/main/examples)或[笔记](https://huggingface.co/docs/transformers/notebooks)以了解此方法的实际操作。
+
+一旦创建了 `tf.data.Dataset`,您可以像以前一样编译和训练模型:
+
+```py
+model.compile(optimizer=Adam(3e-5)) # No loss argument!
+
+model.fit(tf_dataset)
+```
+
+
+
+
+
+
+
+
+如果没有 GPU,可以通过notebook平台如 [Colaboratory](https://colab.research.google.com/) 或 [SageMaker StudioLab](https://studiolab.sagemaker.aws/) 来免费获得云端GPU使用。
+
+
+
+现在您已经准备好训练了!🥳
+
+### 训练循环
+
+为了跟踪训练进度,使用 [tqdm](https://tqdm.github.io/) 库来添加一个进度条,显示训练步数的进展:
+
+```py
+>>> from tqdm.auto import tqdm
+
+>>> progress_bar = tqdm(range(num_training_steps))
+
+>>> model.train()
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... outputs = model(**batch)
+... loss = outputs.loss
+... loss.backward()
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+### 评估
+
+就像您在 [`Trainer`] 中添加了一个评估函数一样,当您编写自己的训练循环时,您需要做同样的事情。但与在每个`epoch`结束时计算和展示指标不同,这一次您将使用 [`~evaluate.add_batch`] 累积所有批次,并在最后计算指标。
+
+```py
+>>> import evaluate
+
+>>> metric = evaluate.load("accuracy")
+>>> model.eval()
+>>> for batch in eval_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... with torch.no_grad():
+... outputs = model(**batch)
+
+... logits = outputs.logits
+... predictions = torch.argmax(logits, dim=-1)
+... metric.add_batch(predictions=predictions, references=batch["labels"])
+
+>>> metric.compute()
+```
+
+
+
+
+ Examples for older versions of 🤗 Transformers
+
+
+
+Alternatively, you can switch your cloned 🤗 Transformers to a specific version (for instance with v3.5.1) with
+```bash
+git checkout tags/v3.5.1
+```
+and run the example command as usual afterward.
+
+## Running the Examples on Remote Hardware with Auto-Setup
+
+[run_on_remote.py](./run_on_remote.py) is a script that launches any example on remote self-hosted hardware,
+with automatic hardware and environment setup. It uses [Runhouse](https://github.com/run-house/runhouse) to launch
+on self-hosted hardware (e.g. in your own cloud account or on-premise cluster) but there are other options
+for running remotely as well. You can easily customize the example used, command line arguments, dependencies,
+and type of compute hardware, and then run the script to automatically launch the example.
+
+You can refer to
+[hardware setup](https://www.run.house/docs/tutorials/quick-start-cloud)
+for more information about hardware and dependency setup with Runhouse, or this
+[Colab tutorial](https://colab.research.google.com/drive/1sh_aNQzJX5BKAdNeXthTNGxKz7sM9VPc) for a more in-depth
+walkthrough.
+
+You can run the script with the following commands:
+
+```bash
+# First install runhouse:
+pip install runhouse
+
+# For an on-demand V100 with whichever cloud provider you have configured:
+python run_on_remote.py \
+ --example pytorch/text-generation/run_generation.py \
+ --model_type=gpt2 \
+ --model_name_or_path=openai-community/gpt2 \
+ --prompt "I am a language model and"
+
+# For byo (bring your own) cluster:
+python run_on_remote.py --host --user --key_path \
+ --example
+
+# For on-demand instances
+python run_on_remote.py --instance --provider \
+ --example
+```
+
+You can also adapt the script to your own needs.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..074aaa292ceb1d586d855a7c674a97be37c5513d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/README.md
@@ -0,0 +1,83 @@
+
+
+# JAX/Flax Examples
+
+This folder contains actively maintained examples of 🤗 Transformers using the JAX/Flax backend. Porting models and examples to JAX/Flax is an ongoing effort, and more will be added in the coming months. In particular, these examples are all designed to run fast on Cloud TPUs, and we include step-by-step guides to getting started with Cloud TPU.
+
+*NOTE*: Currently, there is no "Trainer" abstraction for JAX/Flax -- all examples contain an explicit training loop.
+
+The following table lists all of our examples on how to use 🤗 Transformers with the JAX/Flax backend:
+- with information about the model and dataset used,
+- whether or not they leverage the [🤗 Datasets](https://github.com/huggingface/datasets) library,
+- links to **Colab notebooks** to walk through the scripts and run them easily.
+
+| Task | Example model | Example dataset | 🤗 Datasets | Colab
+|---|---|---|:---:|:---:|
+| [**`causal-language-modeling`**](https://github.com/huggingface/transformers/tree/main/examples/flax/language-modeling) | GPT2 | OSCAR | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/causal_language_modeling_flax.ipynb)
+| [**`masked-language-modeling`**](https://github.com/huggingface/transformers/tree/main/examples/flax/language-modeling) | RoBERTa | OSCAR | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/masked_language_modeling_flax.ipynb)
+| [**`text-classification`**](https://github.com/huggingface/transformers/tree/main/examples/flax/text-classification) | BERT | GLUE | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification_flax.ipynb)
+
+## Intro: JAX and Flax
+
+[JAX](https://github.com/google/jax) is a numerical computation library that exposes a NumPy-like API with tracing capabilities. With JAX's `jit`, you can
+trace pure functions and compile them into efficient, fused accelerator code on both GPU and TPU. JAX
+supports additional transformations such as `grad` (for arbitrary gradients), `pmap` (for parallelizing computation on multiple devices), `remat` (for gradient checkpointing), `vmap` (automatic
+efficient vectorization), and `pjit` (for automatically sharded model parallelism). All JAX transformations compose arbitrarily with each other -- e.g., efficiently
+computing per-example gradients is simply `vmap(grad(f))`.
+
+[Flax](https://github.com/google/flax) builds on top of JAX with an ergonomic
+module abstraction using Python dataclasses that leads to concise and explicit code. Flax's "lifted" JAX transformations (e.g. `vmap`, `remat`) allow you to nest JAX transformation and modules in any way you wish. Flax is the most widely used JAX library, with [129 dependent projects](https://github.com/google/flax/network/dependents?package_id=UGFja2FnZS01MjEyMjA2MA%3D%3D) as of May 2021. It is also the library underlying all of the official Cloud TPU JAX examples.
+
+## Running on Cloud TPU
+
+All of our JAX/Flax models are designed to run efficiently on Google
+Cloud TPUs. Here is [a guide for running JAX on Google Cloud TPU](https://cloud.google.com/tpu/docs/jax-quickstart-tpu-vm).
+
+Consider applying for the [Google TPU Research Cloud project](https://sites.research.google/trc/) for free TPU compute.
+
+Each example README contains more details on the specific model and training
+procedure.
+
+
+## Running on single or multiple GPUs
+
+All of our JAX/Flax examples also run efficiently on single and multiple GPUs. You can use the same instructions in the README to launch training on GPU.
+Distributed training is supported out-of-the box and scripts will use all the GPUs that are detected.
+
+You should follow this [guide for installing JAX on GPUs](https://github.com/google/jax/#pip-installation-gpu-cuda) since the installation depends on
+your CUDA and CuDNN version.
+
+## Supported models
+
+Porting models from PyTorch to JAX/Flax is an ongoing effort.
+Feel free to reach out if you are interested in contributing a model in JAX/Flax -- we'll
+be adding a guide for porting models from PyTorch in the upcoming few weeks.
+
+For a complete overview of models that are supported in JAX/Flax, please have a look at [this](https://huggingface.co/transformers/main/index.html#supported-frameworks) table.
+
+Over 3000 pretrained checkpoints are supported in JAX/Flax as of May 2021.
+Click [here](https://huggingface.co/models?filter=jax) to see the full list on the 🤗 hub.
+
+## Upload the trained/fine-tuned model to the Hub
+
+All the example scripts support automatic upload of your final model to the [Model Hub](https://huggingface.co/models) by adding a `--push_to_hub` argument. It will then create a repository with your username slash the name of the folder you are using as `output_dir`. For instance, `"sgugger/test-mrpc"` if your username is `sgugger` and you are working in the folder `~/tmp/test-mrpc`.
+
+To specify a given repository name, use the `--hub_model_id` argument. You will need to specify the whole repository name (including your username), for instance `--hub_model_id sgugger/finetuned-bert-mrpc`. To upload to an organization you are a member of, just use the name of that organization instead of your username: `--hub_model_id huggingface/finetuned-bert-mrpc`.
+
+A few notes on this integration:
+
+- you will need to be logged in to the Hugging Face website locally for it to work, the easiest way to achieve this is to run `huggingface-cli login` and then type your username and password when prompted. You can also pass along your authentication token with the `--hub_token` argument.
+- the `output_dir` you pick will either need to be a new folder or a local clone of the distant repository you are using.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/_tests_requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/_tests_requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..2e93a1f2c549fffb24f6fa404b67b70323dea051
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/_tests_requirements.txt
@@ -0,0 +1,10 @@
+datasets >= 1.13.3
+pytest<8.0.1
+conllu
+nltk
+rouge-score
+seqeval
+tensorboard
+evaluate >= 0.2.0
+torch
+accelerate
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/conftest.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/conftest.py
new file mode 100644
index 0000000000000000000000000000000000000000..4cf2e46ef07393af6c9ad4f637ee76e442ba8707
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/conftest.py
@@ -0,0 +1,45 @@
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+# tests directory-specific settings - this file is run automatically
+# by pytest before any tests are run
+
+import sys
+import warnings
+from os.path import abspath, dirname, join
+
+
+# allow having multiple repository checkouts and not needing to remember to rerun
+# `pip install -e '.[dev]'` when switching between checkouts and running tests.
+git_repo_path = abspath(join(dirname(dirname(dirname(__file__))), "src"))
+sys.path.insert(1, git_repo_path)
+
+
+# silence FutureWarning warnings in tests since often we can't act on them until
+# they become normal warnings - i.e. the tests still need to test the current functionality
+warnings.simplefilter(action="ignore", category=FutureWarning)
+
+
+def pytest_addoption(parser):
+ from transformers.testing_utils import pytest_addoption_shared
+
+ pytest_addoption_shared(parser)
+
+
+def pytest_terminal_summary(terminalreporter):
+ from transformers.testing_utils import pytest_terminal_summary_main
+
+ make_reports = terminalreporter.config.getoption("--make-reports")
+ if make_reports:
+ pytest_terminal_summary_main(terminalreporter, id=make_reports)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/image-captioning/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/image-captioning/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..dd2b420639258fbfc31a610d3d1d7609d07a691b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/image-captioning/README.md
@@ -0,0 +1,68 @@
+# Image Captioning (vision-encoder-text-decoder model) training example
+
+The following example showcases how to finetune a vision-encoder-text-decoder model for image captioning
+using the JAX/Flax backend, leveraging 🤗 Transformers library's [FlaxVisionEncoderDecoderModel](https://huggingface.co/docs/transformers/model_doc/vision-encoder-decoder#transformers.FlaxVisionEncoderDecoderModel).
+
+JAX/Flax allows you to trace pure functions and compile them into efficient, fused accelerator code on both GPU and TPU.
+Models written in JAX/Flax are **immutable** and updated in a purely functional
+way which enables simple and efficient model parallelism.
+
+`run_image_captioning_flax.py` is a lightweight example of how to download and preprocess a dataset from the 🤗 Datasets
+library or use your own files (jsonlines or csv), then fine-tune one of the architectures above on it.
+
+For custom datasets in `jsonlines` format please see: https://huggingface.co/docs/datasets/loading_datasets#json-files and you also will find examples of these below.
+
+### Download COCO dataset (2017)
+This example uses COCO dataset (2017) through a custom dataset script, which requires users to manually download the
+COCO dataset before training.
+
+```bash
+mkdir data
+cd data
+wget http://images.cocodataset.org/zips/train2017.zip
+wget http://images.cocodataset.org/zips/val2017.zip
+wget http://images.cocodataset.org/zips/test2017.zip
+wget http://images.cocodataset.org/annotations/annotations_trainval2017.zip
+wget http://images.cocodataset.org/annotations/image_info_test2017.zip
+cd ..
+```
+
+### Create a model from a vision encoder model and a text decoder model
+Next, we create a [FlaxVisionEncoderDecoderModel](https://huggingface.co/docs/transformers/model_doc/visionencoderdecoder#transformers.FlaxVisionEncoderDecoderModel) instance from a pre-trained vision encoder ([ViT](https://huggingface.co/docs/transformers/model_doc/vit#transformers.FlaxViTModel)) and a pre-trained text decoder ([GPT2](https://huggingface.co/docs/transformers/model_doc/gpt2#transformers.FlaxGPT2Model)):
+
+```bash
+python3 create_model_from_encoder_decoder_models.py \
+ --output_dir model \
+ --encoder_model_name_or_path google/vit-base-patch16-224-in21k \
+ --decoder_model_name_or_path openai-community/gpt2
+```
+
+### Train the model
+Finally, we can run the example script to train the model:
+
+```bash
+python3 run_image_captioning_flax.py \
+ --output_dir ./image-captioning-training-results \
+ --model_name_or_path model \
+ --dataset_name ydshieh/coco_dataset_script \
+ --dataset_config_name=2017 \
+ --data_dir $PWD/data \
+ --image_column image_path \
+ --caption_column caption \
+ --do_train --do_eval --predict_with_generate \
+ --num_train_epochs 1 \
+ --eval_steps 500 \
+ --learning_rate 3e-5 --warmup_steps 0 \
+ --per_device_train_batch_size 32 \
+ --per_device_eval_batch_size 32 \
+ --overwrite_output_dir \
+ --max_target_length 32 \
+ --num_beams 8 \
+ --preprocessing_num_workers 16 \
+ --logging_steps 10 \
+ --block_size 16384 \
+ --push_to_hub
+```
+
+This should finish in about 1h30 on Cloud TPU, with validation loss and ROUGE2 score of 2.0153 and 14.64 respectively
+after 1 epoch. Training statistics can be accessed on [Models](https://huggingface.co/ydshieh/image-captioning-training-results/tensorboard).
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/image-captioning/create_model_from_encoder_decoder_models.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/image-captioning/create_model_from_encoder_decoder_models.py
new file mode 100644
index 0000000000000000000000000000000000000000..0ebd1464883874ab5174340870fd28bb3954bf26
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/image-captioning/create_model_from_encoder_decoder_models.py
@@ -0,0 +1,116 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2022 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Create a VisionEncoderDecoderModel instance from pretrained encoder/decoder models.
+
+The cross-attention will be randomly initialized.
+"""
+
+from dataclasses import dataclass, field
+from typing import Optional
+
+from transformers import AutoConfig, AutoImageProcessor, AutoTokenizer, FlaxVisionEncoderDecoderModel, HfArgumentParser
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ output_dir: str = field(
+ metadata={"help": "The output directory where the model will be written."},
+ )
+ encoder_model_name_or_path: str = field(
+ metadata={
+ "help": (
+ "The encoder model checkpoint for weights initialization. "
+ "Don't set if you want to train an encoder model from scratch."
+ )
+ },
+ )
+ decoder_model_name_or_path: str = field(
+ metadata={
+ "help": (
+ "The decoder model checkpoint for weights initialization. "
+ "Don't set if you want to train a decoder model from scratch."
+ )
+ },
+ )
+ encoder_config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained encoder config name or path if not the same as encoder_model_name"}
+ )
+ decoder_config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained decoder config name or path if not the same as decoder_model_name"}
+ )
+
+
+def main():
+ parser = HfArgumentParser((ModelArguments,))
+ (model_args,) = parser.parse_args_into_dataclasses()
+
+ # Load pretrained model and tokenizer
+
+ # Use explicit specified encoder config
+ if model_args.encoder_config_name:
+ encoder_config = AutoConfig.from_pretrained(model_args.encoder_config_name)
+ # Use pretrained encoder model's config
+ else:
+ encoder_config = AutoConfig.from_pretrained(model_args.encoder_model_name_or_path)
+
+ # Use explicit specified decoder config
+ if model_args.decoder_config_name:
+ decoder_config = AutoConfig.from_pretrained(model_args.decoder_config_name)
+ # Use pretrained decoder model's config
+ else:
+ decoder_config = AutoConfig.from_pretrained(model_args.decoder_model_name_or_path)
+
+ # necessary for `from_encoder_decoder_pretrained` when `decoder_config` is passed
+ decoder_config.is_decoder = True
+ decoder_config.add_cross_attention = True
+
+ model = FlaxVisionEncoderDecoderModel.from_encoder_decoder_pretrained(
+ encoder_pretrained_model_name_or_path=model_args.encoder_model_name_or_path,
+ decoder_pretrained_model_name_or_path=model_args.decoder_model_name_or_path,
+ encoder_config=encoder_config,
+ decoder_config=decoder_config,
+ )
+
+ # GPT2 only has bos/eos tokens but not decoder_start/pad tokens
+ decoder_start_token_id = decoder_config.decoder_start_token_id
+ pad_token_id = decoder_config.pad_token_id
+ if decoder_start_token_id is None:
+ decoder_start_token_id = decoder_config.bos_token_id
+ if pad_token_id is None:
+ pad_token_id = decoder_config.eos_token_id
+
+ # This is necessary to make Flax's generate() work
+ model.config.eos_token_id = decoder_config.eos_token_id
+ model.config.decoder_start_token_id = decoder_start_token_id
+ model.config.pad_token_id = pad_token_id
+
+ image_processor = AutoImageProcessor.from_pretrained(model_args.encoder_model_name_or_path)
+
+ tokenizer = AutoTokenizer.from_pretrained(model_args.decoder_model_name_or_path)
+ tokenizer.pad_token = tokenizer.convert_ids_to_tokens(model.config.pad_token_id)
+
+ model.save_pretrained(model_args.output_dir)
+ image_processor.save_pretrained(model_args.output_dir)
+ tokenizer.save_pretrained(model_args.output_dir)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/image-captioning/run_image_captioning_flax.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/image-captioning/run_image_captioning_flax.py
new file mode 100644
index 0000000000000000000000000000000000000000..879372a7523823fd8419f2dbbe7b76c14a4f68c5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/image-captioning/run_image_captioning_flax.py
@@ -0,0 +1,1285 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2022 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library vision-encoder-decoder models for image captioning.
+"""
+
+import json
+import logging
+import os
+import sys
+import time
+from dataclasses import asdict, dataclass, field
+from enum import Enum
+from functools import partial
+from pathlib import Path
+from typing import Callable, Optional
+
+import datasets
+import evaluate
+import jax
+import jax.numpy as jnp
+import nltk # Here to have a nice missing dependency error message early on
+import numpy as np
+import optax
+from datasets import Dataset, load_dataset
+from filelock import FileLock
+from flax import jax_utils, traverse_util
+from flax.jax_utils import unreplicate
+from flax.training import train_state
+from flax.training.common_utils import get_metrics, onehot, shard, shard_prng_key
+from huggingface_hub import HfApi
+from PIL import Image
+from tqdm import tqdm
+
+import transformers
+from transformers import (
+ AutoImageProcessor,
+ AutoTokenizer,
+ FlaxVisionEncoderDecoderModel,
+ HfArgumentParser,
+ is_tensorboard_available,
+)
+from transformers.utils import is_offline_mode, send_example_telemetry
+
+
+logger = logging.getLogger(__name__)
+
+try:
+ nltk.data.find("tokenizers/punkt")
+except (LookupError, OSError):
+ if is_offline_mode():
+ raise LookupError(
+ "Offline mode: run this script without TRANSFORMERS_OFFLINE first to download nltk data files"
+ )
+ with FileLock(".lock") as lock:
+ nltk.download("punkt", quiet=True)
+
+
+# Copied from transformers.models.bart.modeling_flax_bart.shift_tokens_right
+def shift_tokens_right(input_ids: np.ndarray, pad_token_id: int, decoder_start_token_id: int) -> np.ndarray:
+ """
+ Shift input ids one token to the right.
+ """
+ shifted_input_ids = np.zeros_like(input_ids)
+ shifted_input_ids[:, 1:] = input_ids[:, :-1]
+ shifted_input_ids[:, 0] = decoder_start_token_id
+
+ shifted_input_ids = np.where(shifted_input_ids == -100, pad_token_id, shifted_input_ids)
+ return shifted_input_ids
+
+
+@dataclass
+class TrainingArguments:
+ output_dir: str = field(
+ metadata={"help": "The output directory where the model predictions and checkpoints will be written."},
+ )
+ overwrite_output_dir: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Overwrite the content of the output directory. "
+ "Use this to continue training if output_dir points to a checkpoint directory."
+ )
+ },
+ )
+ do_train: bool = field(default=False, metadata={"help": "Whether to run training."})
+ do_eval: bool = field(default=False, metadata={"help": "Whether to run eval on the dev set."})
+ do_predict: bool = field(default=False, metadata={"help": "Whether to run predictions on the test set."})
+ per_device_train_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for training."}
+ )
+ per_device_eval_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for evaluation."}
+ )
+ _block_size_doc = """
+ The default value `0` will preprocess (tokenization + image processing) the whole dataset before training and
+ cache the results. This uses more disk space, but avoids (repeated) processing time during training. This is a
+ good option if your disk space is large enough to store the whole processed dataset.
+ If a positive value is given, the captions in the dataset will be tokenized before training and the results are
+ cached. During training, it iterates the dataset in chunks of size `block_size`. On each block, images are
+ transformed by the image processor with the results being kept in memory (no cache), and batches of size
+ `batch_size` are yielded before processing the next block. This could avoid the heavy disk usage when the
+ dataset is large.
+ """
+ block_size: int = field(default=0, metadata={"help": _block_size_doc})
+ learning_rate: float = field(default=5e-5, metadata={"help": "The initial learning rate for AdamW."})
+ weight_decay: float = field(default=0.0, metadata={"help": "Weight decay for AdamW if we apply some."})
+ adam_beta1: float = field(default=0.9, metadata={"help": "Beta1 for AdamW optimizer"})
+ adam_beta2: float = field(default=0.999, metadata={"help": "Beta2 for AdamW optimizer"})
+ adam_epsilon: float = field(default=1e-8, metadata={"help": "Epsilon for AdamW optimizer."})
+ label_smoothing_factor: float = field(
+ default=0.0, metadata={"help": "The label smoothing epsilon to apply (zero means no label smoothing)."}
+ )
+ num_train_epochs: float = field(default=3.0, metadata={"help": "Total number of training epochs to perform."})
+ warmup_steps: int = field(default=0, metadata={"help": "Linear warmup over warmup_steps."})
+ logging_steps: int = field(default=500, metadata={"help": "Log every X updates steps."})
+ eval_steps: int = field(default=None, metadata={"help": "Run an evaluation every X steps."})
+ seed: int = field(default=42, metadata={"help": "Random seed that will be set at the beginning of training."})
+ push_to_hub: bool = field(
+ default=False, metadata={"help": "Whether or not to upload the trained model to the model hub after training."}
+ )
+ hub_model_id: str = field(
+ default=None, metadata={"help": "The name of the repository to keep in sync with the local `output_dir`."}
+ )
+ hub_token: str = field(default=None, metadata={"help": "The token to use to push to the Model Hub."})
+
+ def __post_init__(self):
+ if self.output_dir is not None:
+ self.output_dir = os.path.expanduser(self.output_dir)
+
+ def to_dict(self):
+ """
+ Serializes this instance while replace `Enum` by their values (for JSON serialization support). It obfuscates
+ the token values by removing their value.
+ """
+ d = asdict(self)
+ for k, v in d.items():
+ if isinstance(v, Enum):
+ d[k] = v.value
+ if isinstance(v, list) and len(v) > 0 and isinstance(v[0], Enum):
+ d[k] = [x.value for x in v]
+ if k.endswith("_token"):
+ d[k] = f"<{k.upper()}>"
+ return d
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "The model checkpoint for weights initialization."},
+ )
+ cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ dtype: Optional[str] = field(
+ default="float32",
+ metadata={
+ "help": (
+ "Floating-point format in which the model weights should be initialized and trained. Choose one of"
+ " `[float32, float16, bfloat16]`."
+ )
+ },
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ data_dir: Optional[str] = field(
+ default=None, metadata={"help": "The data directory of the dataset to use (via the datasets library)."}
+ )
+ image_column: Optional[str] = field(
+ default=None,
+ metadata={"help": "The name of the column in the datasets containing the full image file paths."},
+ )
+ caption_column: Optional[str] = field(
+ default=None,
+ metadata={"help": "The name of the column in the datasets containing the image captions."},
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ test_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input predict data file to do prediction on (a text file)."},
+ )
+ max_target_length: Optional[int] = field(
+ default=128,
+ metadata={
+ "help": (
+ "The maximum total sequence length for target text after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ val_max_target_length: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The maximum total sequence length for validation target text after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded. Will default to `max_target_length`. "
+ "This argument is also used to override the `max_length` param of `model.generate`, which is used "
+ "during evaluation."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_predict_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of prediction examples to this "
+ "value if set."
+ )
+ },
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ predict_with_generate: bool = field(
+ default=False, metadata={"help": "Whether to use generate to calculate generative metrics (ROUGE, BLEU)."}
+ )
+ num_beams: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Number of beams to use for evaluation. This argument will be passed to `model.generate`, "
+ "which is used during evaluation."
+ )
+ },
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+
+ def __post_init__(self):
+ if self.dataset_name is None and self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ if extension not in ["csv", "json"]:
+ raise ValueError(f"`train_file` should be a csv or a json file, got {extension}.")
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ if extension not in ["csv", "json"]:
+ raise ValueError(f"`validation_file` should be a csv or a json file, got {extension}.")
+ if self.val_max_target_length is None:
+ self.val_max_target_length = self.max_target_length
+
+
+image_captioning_name_mapping = {
+ "image_caption_dataset.py": ("image_path", "caption"),
+}
+
+
+class TrainState(train_state.TrainState):
+ dropout_rng: jnp.ndarray
+
+ def replicate(self):
+ return jax_utils.replicate(self).replace(dropout_rng=shard_prng_key(self.dropout_rng))
+
+
+def data_loader(rng: jax.random.PRNGKey, dataset: Dataset, batch_size: int, shuffle: bool = False):
+ """
+ Returns batches of size `batch_size` from truncated `dataset`, sharded over all local devices.
+ Shuffle batches if `shuffle` is `True`.
+ """
+ steps = len(dataset) // batch_size # Skip incomplete batch.
+
+ # We use `numpy.ndarray` to interact with `datasets.Dataset`, since using `jax.numpy.array` to index into a
+ # dataset is significantly slow. Using JAX array at the 1st place is only to keep JAX's PRNGs generation
+ # mechanism, which works differently from NumPy/SciPy.
+ if shuffle:
+ batch_idx = jax.random.permutation(rng, len(dataset))
+ batch_idx = np.asarray(batch_idx)
+ else:
+ batch_idx = np.arange(len(dataset))
+
+ for idx in range(steps):
+ start_idx = batch_size * idx
+ end_idx = batch_size * (idx + 1)
+
+ selected_indices = batch_idx[start_idx:end_idx]
+ batch = dataset[selected_indices]
+ batch = shard(batch)
+
+ yield batch
+
+
+def write_metric(summary_writer, metrics, train_time, step, metric_key_prefix="train"):
+ if train_time:
+ summary_writer.scalar("train_time", train_time, step)
+
+ metrics = get_metrics(metrics)
+ for key, vals in metrics.items():
+ tag = f"{metric_key_prefix}_{key}"
+ for i, val in enumerate(vals):
+ summary_writer.scalar(tag, val, step - len(vals) + i + 1)
+
+ else:
+ for metric_name, value in metrics.items():
+ summary_writer.scalar(f"{metric_key_prefix}_{metric_name}", value, step)
+
+
+def create_learning_rate_fn(
+ train_ds_size: int, train_batch_size: int, num_train_epochs: int, num_warmup_steps: int, learning_rate: float
+) -> Callable[[int], jnp.ndarray]:
+ """Returns a linear warmup, linear_decay learning rate function."""
+ steps_per_epoch = train_ds_size // train_batch_size
+ num_train_steps = steps_per_epoch * num_train_epochs
+ warmup_fn = optax.linear_schedule(init_value=0.0, end_value=learning_rate, transition_steps=num_warmup_steps)
+ decay_fn = optax.linear_schedule(
+ init_value=learning_rate, end_value=0, transition_steps=num_train_steps - num_warmup_steps
+ )
+ schedule_fn = optax.join_schedules(schedules=[warmup_fn, decay_fn], boundaries=[num_warmup_steps])
+ return schedule_fn
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_image_captioning", model_args, data_args, framework="flax")
+
+ if (
+ os.path.exists(training_args.output_dir)
+ and os.listdir(training_args.output_dir)
+ and training_args.do_train
+ and not training_args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ # Setup logging, we only want one process per machine to log things on the screen.
+ logger.setLevel(logging.INFO if jax.process_index() == 0 else logging.ERROR)
+ if jax.process_index() == 0:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Handle the repository creation
+ if training_args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = training_args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(training_args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=training_args.hub_token).repo_id
+
+ # Get the datasets: you can either provide your own CSV/JSON training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files this script will use the first column for the full image path and the second column for the
+ # captions (unless you specify column names for this with the `image_column` and `caption_column` arguments).
+ #
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ dataset = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ keep_in_memory=False,
+ data_dir=data_args.data_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ if data_args.test_file is not None:
+ data_files["test"] = data_args.test_file
+ extension = data_args.test_file.split(".")[-1]
+ dataset = load_dataset(
+ extension,
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+ model = FlaxVisionEncoderDecoderModel.from_pretrained(
+ model_args.model_name_or_path,
+ seed=training_args.seed,
+ dtype=getattr(jnp, model_args.dtype),
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ image_processor = AutoImageProcessor.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ tokenizer.pad_token = tokenizer.convert_ids_to_tokens(model.config.pad_token_id)
+
+ # Preprocessing the datasets.
+ # We need to tokenize inputs and targets.
+ if training_args.do_train:
+ column_names = dataset["train"].column_names
+ elif training_args.do_eval:
+ column_names = dataset["validation"].column_names
+ elif training_args.do_predict:
+ column_names = dataset["test"].column_names
+ else:
+ logger.info("There is nothing to do. Please pass `do_train`, `do_eval` and/or `do_predict`.")
+ return
+
+ # Get the column names for input/target.
+ dataset_columns = image_captioning_name_mapping.get(data_args.dataset_name, None)
+ if data_args.image_column is None:
+ if dataset_columns is None:
+ raise ValueError(
+ f"`--dataset_name` {data_args.dataset_name} not found in dataset '{data_args.dataset_name}'. Make sure"
+ " to set `--dataset_name` to the correct dataset name, one of"
+ f" {', '.join(image_captioning_name_mapping.keys())}."
+ )
+ image_column = dataset_columns[0]
+ else:
+ image_column = data_args.image_column
+ if image_column not in column_names:
+ raise ValueError(
+ f"--image_column' value '{data_args.image_column}' needs to be one of: {', '.join(column_names)}"
+ )
+ if data_args.caption_column is None:
+ if dataset_columns is None:
+ raise ValueError(
+ f"`--dataset_name` {data_args.dataset_name} not found in dataset '{data_args.dataset_name}'. Make sure"
+ " to set `--dataset_name` to the correct dataset name, one of"
+ f" {', '.join(image_captioning_name_mapping.keys())}."
+ )
+ caption_column = dataset_columns[1]
+ else:
+ caption_column = data_args.caption_column
+ if caption_column not in column_names:
+ raise ValueError(
+ f"--caption_column' value '{data_args.caption_column}' needs to be one of: {', '.join(column_names)}"
+ )
+
+ # In Flax, for seq2seq models we need to pass `decoder_input_ids`
+ # as the Flax models don't accept `labels`, we need to prepare the decoder_input_ids here
+ # for that dynamically import the `shift_tokens_right` function from the model file
+ model_module = __import__(model.__module__, fromlist=["shift_tokens_right"])
+ shift_tokens_right_fn = getattr(model_module, "shift_tokens_right", shift_tokens_right)
+
+ def filter_fn(examples):
+ """remove problematic images"""
+
+ bools = []
+ for image_file in examples[image_column]:
+ try:
+ image = Image.open(image_file)
+ image_processor(images=image, return_tensors="np")
+ bools.append(True)
+ except Exception:
+ bools.append(False)
+
+ return bools
+
+ # Setting padding="max_length" as we need fixed length inputs for jitted functions
+ def tokenization_fn(examples, max_target_length):
+ """Run tokenization on captions."""
+
+ captions = []
+ for caption in examples[caption_column]:
+ captions.append(caption.lower() + " " + tokenizer.eos_token)
+ targets = captions
+
+ model_inputs = {}
+
+ labels = tokenizer(
+ text_target=targets,
+ max_length=max_target_length,
+ padding="max_length",
+ truncation=True,
+ return_tensors="np",
+ )
+ model_inputs["labels"] = labels["input_ids"]
+ decoder_input_ids = shift_tokens_right_fn(
+ labels["input_ids"], model.config.pad_token_id, model.config.decoder_start_token_id
+ )
+ model_inputs["decoder_input_ids"] = np.asarray(decoder_input_ids)
+ # We need decoder_attention_mask so we can ignore pad tokens from loss
+ model_inputs["decoder_attention_mask"] = labels["attention_mask"]
+ model_inputs[image_column] = examples[image_column]
+
+ return model_inputs
+
+ def image_processing_fn(examples, check_image=True):
+ """
+ Run preprocessing on images
+
+ If `check_image` is `True`, the examples that fails during `Image.open()` will be caught and discarded.
+ Otherwise, an exception will be thrown.
+ """
+
+ model_inputs = {}
+
+ if check_image:
+ images = []
+ to_keep = []
+ for image_file in examples[image_column]:
+ try:
+ img = Image.open(image_file)
+ images.append(img)
+ to_keep.append(True)
+ except Exception:
+ to_keep.append(False)
+
+ for k, v in examples.items():
+ if k != image_column:
+ model_inputs[k] = v[to_keep]
+ else:
+ images = [Image.open(image_file) for image_file in examples[image_column]]
+
+ encoder_inputs = image_processor(images=images, return_tensors="np")
+ model_inputs["pixel_values"] = encoder_inputs.pixel_values
+
+ return model_inputs
+
+ def preprocess_fn(examples, max_target_length, check_image=True):
+ """Run tokenization + image processing"""
+
+ model_inputs = {}
+ # This contains image path column
+ model_inputs.update(tokenization_fn(examples, max_target_length))
+ model_inputs.update(image_processing_fn(model_inputs, check_image=check_image))
+ # Remove image path column
+ model_inputs.pop(image_column)
+
+ return model_inputs
+
+ features = datasets.Features(
+ {
+ "pixel_values": datasets.Array3D(
+ shape=(
+ getattr(model.config.encoder, "num_channels", 3),
+ model.config.encoder.image_size,
+ model.config.encoder.image_size,
+ ),
+ dtype="float32",
+ ),
+ "labels": datasets.Sequence(feature=datasets.Value(dtype="int32", id=None), length=-1, id=None),
+ "decoder_input_ids": datasets.Sequence(feature=datasets.Value(dtype="int32", id=None), length=-1, id=None),
+ "decoder_attention_mask": datasets.Sequence(
+ feature=datasets.Value(dtype="int32", id=None), length=-1, id=None
+ ),
+ }
+ )
+
+ # If `block_size` is `0`, tokenization & image processing is done at the beginning
+ run_img_proc_at_beginning = training_args.block_size == 0
+ # Used in .map() below
+ function_kwarg = preprocess_fn if run_img_proc_at_beginning else tokenization_fn
+ # `features` is used only for the final preprocessed dataset (for the performance purpose).
+ features_kwarg = features if run_img_proc_at_beginning else None
+ # Keep `image_column` if the image processing is done during training
+ remove_columns_kwarg = [x for x in column_names if x != image_column or run_img_proc_at_beginning]
+ processor_names = "tokenizer and image processor" if run_img_proc_at_beginning else "tokenizer"
+
+ # Store some constant
+ train_batch_size = int(training_args.per_device_train_batch_size) * jax.device_count()
+ eval_batch_size = int(training_args.per_device_eval_batch_size) * jax.device_count()
+ if training_args.block_size % train_batch_size > 0 or training_args.block_size % eval_batch_size > 0:
+ raise ValueError(
+ "`training_args.block_size` needs to be a multiple of the global train/eval batch size. "
+ f"Got {training_args.block_size}, {train_batch_size} and {eval_batch_size} respectively instead."
+ )
+
+ if training_args.do_train:
+ if "train" not in dataset:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = dataset["train"]
+ if data_args.max_train_samples is not None:
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+ # remove problematic examples
+ # (if image processing is performed at the beginning, the filtering is done during preprocessing below
+ # instead here.)
+ if not run_img_proc_at_beginning:
+ train_dataset = train_dataset.filter(filter_fn, batched=True, num_proc=data_args.preprocessing_num_workers)
+ train_dataset = train_dataset.map(
+ function=function_kwarg,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ # kept image paths
+ remove_columns=remove_columns_kwarg,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc=f"Running {processor_names} on train dataset",
+ fn_kwargs={"max_target_length": data_args.max_target_length},
+ features=features_kwarg,
+ )
+ if run_img_proc_at_beginning:
+ # set format (for performance) since the dataset is ready to be used
+ train_dataset = train_dataset.with_format("numpy")
+
+ steps_per_epoch = len(train_dataset) // train_batch_size
+ num_train_examples_per_epoch = steps_per_epoch * train_batch_size
+ num_epochs = int(training_args.num_train_epochs)
+ total_train_steps = steps_per_epoch * num_epochs
+ else:
+ num_train_examples_per_epoch = 0
+
+ if training_args.do_eval:
+ if "validation" not in dataset:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_dataset = dataset["validation"]
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+ # remove problematic examples
+ # (if image processing is performed at the beginning, the filtering is done during preprocessing below
+ # instead here.)
+ if not run_img_proc_at_beginning:
+ eval_dataset = eval_dataset.filter(filter_fn, batched=True, num_proc=data_args.preprocessing_num_workers)
+ eval_dataset = eval_dataset.map(
+ function=function_kwarg,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ # kept image paths
+ remove_columns=remove_columns_kwarg,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc=f"Running {processor_names} on validation dataset",
+ fn_kwargs={"max_target_length": data_args.val_max_target_length},
+ features=features_kwarg,
+ )
+ if run_img_proc_at_beginning:
+ # set format (for performance) since the dataset is ready to be used
+ eval_dataset = eval_dataset.with_format("numpy")
+
+ num_eval_examples = len(eval_dataset)
+ eval_steps = num_eval_examples // eval_batch_size
+
+ if training_args.do_predict:
+ if "test" not in dataset:
+ raise ValueError("--do_predict requires a test dataset")
+ predict_dataset = dataset["test"]
+ if data_args.max_predict_samples is not None:
+ max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
+ predict_dataset = predict_dataset.select(range(max_predict_samples))
+ # remove problematic examples
+ # (if image processing is performed at the beginning, the filtering is done during preprocessing below
+ # instead here.)
+ if not run_img_proc_at_beginning:
+ predict_dataset = predict_dataset.filter(
+ filter_fn, batched=True, num_proc=data_args.preprocessing_num_workers
+ )
+ predict_dataset = predict_dataset.map(
+ function=function_kwarg,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ # kept image paths
+ remove_columns=remove_columns_kwarg,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc=f"Running {processor_names} on prediction dataset",
+ fn_kwargs={"max_target_length": data_args.val_max_target_length},
+ features=features_kwarg,
+ )
+ if run_img_proc_at_beginning:
+ # set format (for performance) since the dataset is ready to be used
+ predict_dataset = predict_dataset.with_format("numpy")
+
+ num_test_examples = len(predict_dataset)
+ test_steps = num_test_examples // eval_batch_size
+
+ def blockwise_data_loader(
+ rng: jax.random.PRNGKey,
+ ds: Dataset,
+ block_size: int,
+ batch_size: int,
+ shuffle: bool = False,
+ keep_in_memory: bool = False,
+ split: str = "",
+ ):
+ """
+ Wrap the simple `data_loader` in a block-wise way if `block_size` > 0, else it's the same as `data_loader`.
+
+ If `block_size` > 0, it requires `ds` to have a column that gives image paths in order to perform image
+ processing (with the column name being specified by `image_column`). The tokenization should be done before
+ training in this case.
+ """
+
+ # We use `numpy.ndarray` to interact with `datasets.Dataset`, since using `jax.numpy.array` to index into a
+ # dataset is significantly slow. Using JAX array at the 1st place is only to keep JAX's PRNGs generation
+ # mechanism, which works differently from NumPy/SciPy.
+ if shuffle:
+ indices = jax.random.permutation(rng, len(ds))
+ indices = np.asarray(indices)
+ else:
+ indices = np.arange(len(ds))
+
+ _block_size = len(ds) if not block_size else block_size
+
+ steps_per_block = _block_size // batch_size
+ num_examples = len(ds)
+ steps = num_examples // batch_size
+ num_splits = steps // steps_per_block + int(steps % steps_per_block > 0)
+
+ for idx in range(num_splits):
+ if not block_size:
+ _ds = ds
+ else:
+ start_idx = block_size * idx
+ end_idx = block_size * (idx + 1)
+
+ selected_indices = indices[start_idx:end_idx]
+
+ _ds = ds.select(selected_indices)
+
+ _ds = _ds.map(
+ image_processing_fn,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=[image_column],
+ load_from_cache_file=not data_args.overwrite_cache,
+ features=features,
+ keep_in_memory=keep_in_memory,
+ # The images are already checked either in `.filter()` or in `preprocess_fn()`
+ fn_kwargs={"check_image": False},
+ desc=f"Running image processing on {split} dataset".replace(" ", " "),
+ )
+ _ds = _ds.with_format("numpy")
+
+ # No need to shuffle here
+ loader = data_loader(rng, _ds, batch_size=batch_size, shuffle=False)
+
+ for batch in loader:
+ yield batch
+
+ # Metric
+ metric = evaluate.load("rouge", cache_dir=model_args.cache_dir)
+
+ def postprocess_text(preds, labels):
+ preds = [pred.strip() for pred in preds]
+ labels = [label.strip() for label in labels]
+
+ # rougeLSum expects newline after each sentence
+ preds = ["\n".join(nltk.sent_tokenize(pred)) for pred in preds]
+ labels = ["\n".join(nltk.sent_tokenize(label)) for label in labels]
+
+ return preds, labels
+
+ def compute_metrics(preds, labels):
+ decoded_preds = tokenizer.batch_decode(preds, skip_special_tokens=True)
+ decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+ # Some simple post-processing
+ decoded_preds, decoded_labels = postprocess_text(decoded_preds, decoded_labels)
+
+ result = metric.compute(predictions=decoded_preds, references=decoded_labels, use_stemmer=True)
+ # Extract a few results from ROUGE
+ result = {key: value.mid.fmeasure * 100 for key, value in result.items()}
+
+ prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in preds]
+ result["gen_len"] = np.mean(prediction_lens)
+ result = {k: round(v, 6) for k, v in result.items()}
+
+ return result, decoded_preds, decoded_labels
+
+ # Enable tensorboard only on the master node
+ has_tensorboard = is_tensorboard_available()
+ if has_tensorboard and jax.process_index() == 0:
+ try:
+ from flax.metrics.tensorboard import SummaryWriter
+
+ summary_writer = SummaryWriter(log_dir=Path(training_args.output_dir))
+ except ImportError as ie:
+ has_tensorboard = False
+ logger.warning(
+ f"Unable to display metrics through TensorBoard because some package are not installed: {ie}"
+ )
+ else:
+ logger.warning(
+ "Unable to display metrics through TensorBoard because the package is not installed: "
+ "Please run pip install tensorboard to enable."
+ )
+
+ # Initialize our training
+ rng = jax.random.PRNGKey(training_args.seed)
+ rng, dropout_rng = jax.random.split(rng)
+
+ # Create learning rate schedule
+ linear_decay_lr_schedule_fn = create_learning_rate_fn(
+ num_train_examples_per_epoch,
+ train_batch_size,
+ training_args.num_train_epochs,
+ training_args.warmup_steps,
+ training_args.learning_rate,
+ )
+
+ # We use Optax's "masking" functionality to not apply weight decay
+ # to bias and LayerNorm scale parameters. decay_mask_fn returns a
+ # mask boolean with the same structure as the parameters.
+ # The mask is True for parameters that should be decayed.
+ def decay_mask_fn(params):
+ flat_params = traverse_util.flatten_dict(params)
+ # find out all LayerNorm parameters
+ layer_norm_candidates = ["layernorm", "layer_norm", "ln"]
+ layer_norm_named_params = {
+ layer[-2:]
+ for layer_norm_name in layer_norm_candidates
+ for layer in flat_params.keys()
+ if layer_norm_name in "".join(layer).lower()
+ }
+ flat_mask = {path: (path[-1] != "bias" and path[-2:] not in layer_norm_named_params) for path in flat_params}
+ return traverse_util.unflatten_dict(flat_mask)
+
+ # create adam optimizer
+ adamw = optax.adamw(
+ learning_rate=linear_decay_lr_schedule_fn,
+ b1=training_args.adam_beta1,
+ b2=training_args.adam_beta2,
+ eps=training_args.adam_epsilon,
+ weight_decay=training_args.weight_decay,
+ mask=decay_mask_fn,
+ )
+
+ # Setup train state
+ state = TrainState.create(apply_fn=model.__call__, params=model.params, tx=adamw, dropout_rng=dropout_rng)
+
+ # label smoothed cross entropy
+ def loss_fn(logits, labels, padding_mask, label_smoothing_factor=0.0):
+ """
+ The label smoothing implementation is adapted from Flax's official example:
+ https://github.com/google/flax/blob/87a211135c6a377c8f29048a1cac3840e38b9da4/examples/wmt/train.py#L104
+ """
+ vocab_size = logits.shape[-1]
+ confidence = 1.0 - label_smoothing_factor
+ low_confidence = (1.0 - confidence) / (vocab_size - 1)
+ normalizing_constant = -(
+ confidence * jnp.log(confidence) + (vocab_size - 1) * low_confidence * jnp.log(low_confidence + 1e-20)
+ )
+ soft_labels = onehot(labels, vocab_size, on_value=confidence, off_value=low_confidence)
+
+ loss = optax.softmax_cross_entropy(logits, soft_labels)
+ loss = loss - normalizing_constant
+
+ # ignore padded tokens from loss
+ loss = loss * padding_mask
+ loss = loss.sum()
+ num_labels = padding_mask.sum()
+ return loss, num_labels
+
+ # Define gradient update step fn
+ def train_step(state, batch, label_smoothing_factor=0.0):
+ dropout_rng, new_dropout_rng = jax.random.split(state.dropout_rng)
+
+ def compute_loss(params):
+ labels = batch.pop("labels")
+ logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
+ loss, num_labels = loss_fn(logits, labels, batch["decoder_attention_mask"], label_smoothing_factor)
+ return loss, num_labels
+
+ grad_fn = jax.value_and_grad(compute_loss, has_aux=True)
+ (loss, num_labels), grad = grad_fn(state.params)
+ num_labels = jax.lax.psum(num_labels, "batch")
+
+ # true loss = total loss / total samples
+ loss = jax.lax.psum(loss, "batch")
+ loss = jax.tree_util.tree_map(lambda x: x / num_labels, loss)
+
+ # true grad = total grad / total samples
+ grad = jax.lax.psum(grad, "batch")
+ grad = jax.tree_util.tree_map(lambda x: x / num_labels, grad)
+ new_state = state.apply_gradients(grads=grad, dropout_rng=new_dropout_rng)
+
+ metrics = {"loss": loss, "learning_rate": linear_decay_lr_schedule_fn(state.step)}
+ return new_state, metrics
+
+ # Define eval fn
+ def eval_step(params, batch, label_smoothing_factor=0.0):
+ labels = batch.pop("labels")
+ logits = model(**batch, params=params, train=False)[0]
+
+ loss, num_labels = loss_fn(logits, labels, batch["decoder_attention_mask"], label_smoothing_factor)
+ num_labels = jax.lax.psum(num_labels, "batch")
+
+ # true loss = total loss / total samples
+ loss = jax.lax.psum(loss, "batch")
+ loss = jax.tree_util.tree_map(lambda x: x / num_labels, loss)
+
+ metrics = {"loss": loss}
+ return metrics
+
+ # Define generation function
+ max_length = (
+ data_args.val_max_target_length if data_args.val_max_target_length is not None else model.config.max_length
+ )
+ num_beams = data_args.num_beams if data_args.num_beams is not None else model.config.num_beams
+ gen_kwargs = {"max_length": max_length, "num_beams": num_beams}
+
+ def generate_step(params, batch):
+ model.params = params
+ output_ids = model.generate(batch["pixel_values"], **gen_kwargs)
+ return output_ids.sequences
+
+ # Create parallel version of the train and eval step
+ p_train_step = jax.pmap(
+ partial(train_step, label_smoothing_factor=training_args.label_smoothing_factor), "batch", donate_argnums=(0,)
+ )
+ p_eval_step = jax.pmap(partial(eval_step, label_smoothing_factor=training_args.label_smoothing_factor), "batch")
+ p_generate_step = jax.pmap(generate_step, "batch")
+
+ # Replicate the train state on each device
+ state = state.replicate()
+
+ if training_args.do_train:
+ logger.info("***** Running training *****")
+ logger.info(f" Num train examples = {num_train_examples_per_epoch}")
+ logger.info(f" Num Epochs = {num_epochs}")
+ logger.info(f" Instantaneous train batch size per device = {training_args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel & distributed) = {train_batch_size}")
+ logger.info(f" Optimization steps per epoch = {steps_per_epoch}")
+ logger.info(f" Total optimization steps = {total_train_steps}")
+ if training_args.do_eval:
+ logger.info(f" Num evaluation examples = {num_eval_examples}")
+ logger.info(f" Instantaneous evaluation batch size per device = {training_args.per_device_eval_batch_size}")
+ logger.info(f" Total evaluation batch size (w. parallel & distributed) = {eval_batch_size}")
+ logger.info(f" Evaluation steps = {eval_steps}")
+ if training_args.do_predict:
+ logger.info(f" Num test examples = {num_test_examples}")
+ logger.info(f" Instantaneous test batch size per device = {training_args.per_device_eval_batch_size}")
+ logger.info(f" Total test batch size (w. parallel & distributed) = {eval_batch_size}")
+ logger.info(f" Test steps = {test_steps}")
+
+ # create output directory
+ if not os.path.isdir(os.path.join(training_args.output_dir)):
+ os.makedirs(os.path.join(training_args.output_dir), exist_ok=True)
+
+ def save_ckpt(ckpt_dir: str, commit_msg: str = ""):
+ """save checkpoints and push to Hugging Face Hub if specified"""
+
+ # save checkpoint after each epoch and push checkpoint to the hub
+ if jax.process_index() == 0:
+ params = jax.device_get(jax.tree_util.tree_map(lambda x: x[0], state.params))
+ model.save_pretrained(os.path.join(training_args.output_dir, ckpt_dir), params=params)
+ tokenizer.save_pretrained(os.path.join(training_args.output_dir, ckpt_dir))
+ if training_args.push_to_hub:
+ api.upload_folder(
+ commit_message=commit_msg,
+ folder_path=training_args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=training_args.hub_token,
+ )
+
+ def evaluation_loop(
+ rng: jax.random.PRNGKey,
+ dataset: Dataset,
+ metric_key_prefix: str = "eval",
+ ckpt_dir: str = "",
+ is_prediction=False,
+ ):
+ logger.info(f"*** {'Predict' if is_prediction else 'Evaluate'} ***")
+
+ metrics = []
+ preds = []
+ labels = []
+
+ batches = blockwise_data_loader(
+ rng,
+ dataset,
+ block_size=training_args.block_size,
+ batch_size=eval_batch_size,
+ keep_in_memory=False,
+ shuffle=False,
+ split="prediction" if is_prediction else "validation",
+ )
+ steps = len(dataset) // eval_batch_size
+ for _ in tqdm(
+ range(steps), desc=f"{'Predicting' if is_prediction else 'Evaluating'}...", position=2, leave=False
+ ):
+ # Model forward
+ batch = next(batches)
+ _labels = batch.get("labels", None)
+ if not is_prediction and _labels is None:
+ raise ValueError("Evaluation requires the validation dataset to have `labels`")
+
+ if _labels is not None:
+ _metrics = p_eval_step(state.params, batch)
+ metrics.append(_metrics)
+
+ # generation
+ if data_args.predict_with_generate:
+ generated_ids = p_generate_step(state.params, batch)
+ preds.extend(jax.device_get(generated_ids.reshape(-1, gen_kwargs["max_length"])))
+ if _labels is not None:
+ labels.extend(jax.device_get(_labels.reshape(-1, _labels.shape[-1])))
+
+ if metrics:
+ # normalize metrics
+ metrics = get_metrics(metrics)
+ metrics = jax.tree_util.tree_map(jnp.mean, metrics)
+
+ # compute ROUGE metrics
+ generations = []
+ rouge_desc = ""
+ if data_args.predict_with_generate:
+ if labels:
+ rouge_metrics, decoded_preds, decoded_labels = compute_metrics(preds, labels)
+ metrics.update(rouge_metrics)
+ rouge_desc = " ".join(
+ [
+ f"{'Predict' if is_prediction else 'Eval'} {key}: {value} |"
+ for key, value in rouge_metrics.items()
+ ]
+ )
+ for pred, label in zip(decoded_preds, decoded_labels):
+ pred = pred.replace("\n", " ")
+ label = label.replace("\n", " ")
+ generations.append({"label": label, "pred": pred})
+ else:
+ decoded_preds = tokenizer.batch_decode(preds, skip_special_tokens=True)
+ # Some simple post-processing
+ decoded_preds = [pred.strip() for pred in decoded_preds]
+ # rougeLSum expects newline after each sentence
+ decoded_preds = ["\n".join(nltk.sent_tokenize(pred)) for pred in decoded_preds]
+ for pred in decoded_preds:
+ pred = pred.replace("\n", " ")
+ generations.append({"pred": pred})
+
+ if metrics:
+ # Print metrics and update progress bar
+ desc = f"{'Predict' if is_prediction else 'Eval'} Loss: {metrics['loss']} | {rouge_desc})"
+ if training_args.do_train and not is_prediction:
+ desc = f"Epoch... ({epoch + 1}/{num_epochs} | Step: {cur_step} | " + desc
+ epochs.write(desc)
+ epochs.desc = desc
+ logger.info(desc)
+
+ if jax.process_index() == 0:
+ if not os.path.isdir(os.path.join(training_args.output_dir, ckpt_dir)):
+ os.makedirs(os.path.join(training_args.output_dir, ckpt_dir), exist_ok=True)
+
+ if metrics:
+ # Save metrics (only for the evaluation/prediction being done along with training)
+ if has_tensorboard and training_args.do_train:
+ write_metric(
+ summary_writer, metrics, train_time=None, step=cur_step, metric_key_prefix=metric_key_prefix
+ )
+
+ # save final metrics in json
+ metrics = {
+ f"{metric_key_prefix}_{metric_name}": round(value.item(), 6)
+ for metric_name, value in metrics.items()
+ }
+ _path = os.path.join(training_args.output_dir, ckpt_dir, f"{metric_key_prefix}_results.json")
+ with open(_path, "w") as f:
+ json.dump(metrics, f, indent=4, sort_keys=True)
+
+ # Update report
+ with open(os.path.join(training_args.output_dir, "log"), "a", encoding="UTF-8") as fp:
+ fp.write(desc + "\n")
+
+ # Save generations
+ if generations:
+ output_file = os.path.join(training_args.output_dir, ckpt_dir, f"{metric_key_prefix}_generation.json")
+ with open(output_file, "w", encoding="UTF-8") as fp:
+ json.dump(generations, fp, ensure_ascii=False, indent=4)
+
+ def evaluate(rng: jax.random.PRNGKey, dataset: Dataset, ckpt_dir: str = ""):
+ evaluation_loop(rng, dataset, metric_key_prefix="eval", ckpt_dir=ckpt_dir)
+
+ def predict(rng: jax.random.PRNGKey, dataset: Dataset):
+ evaluation_loop(rng, dataset, metric_key_prefix="test", is_prediction=True)
+
+ input_rng = None
+
+ if training_args.do_train:
+ cur_step = 0
+ train_time = 0
+ epochs = tqdm(range(num_epochs), desc=f"Epoch ... (1/{num_epochs})", position=0)
+
+ for epoch in epochs:
+ # ======================== Training ================================
+ # Create sampling rng
+ rng, input_rng = jax.random.split(rng)
+
+ train_metrics = []
+ train_batches = blockwise_data_loader(
+ input_rng,
+ train_dataset,
+ block_size=training_args.block_size,
+ batch_size=train_batch_size,
+ keep_in_memory=True,
+ shuffle=True,
+ split="train",
+ )
+
+ # train
+ for batch_idx, _ in enumerate(tqdm(range(steps_per_epoch), desc="Training...", position=1, leave=False)):
+ cur_step += 1
+ batch = next(train_batches)
+ batch_start = time.time()
+ state, train_metric = p_train_step(state, batch)
+ train_metrics.append(train_metric)
+ train_time += time.time() - batch_start
+ time_per_step = train_time / cur_step
+
+ # log and save info
+ if training_args.logging_steps > 0 and cur_step % training_args.logging_steps == 0:
+ _train_metric = unreplicate(train_metric)
+ desc = (
+ f"Epoch... ({epoch + 1}/{num_epochs} | Step: {cur_step} | Loss: {_train_metric['loss']} |"
+ f" Learning Rate: {_train_metric['learning_rate']} | Time per step: {time_per_step})"
+ )
+ epochs.desc = desc
+ epochs.write(desc)
+
+ logger.info(desc)
+
+ with open(os.path.join(training_args.output_dir, "log"), "a", encoding="UTF-8") as fp:
+ fp.write(desc + "\n")
+
+ # Save metrics
+ if has_tensorboard and jax.process_index() == 0:
+ write_metric(
+ summary_writer,
+ train_metrics,
+ train_time=train_time,
+ step=cur_step,
+ metric_key_prefix="train",
+ )
+
+ # ======================== Evaluating (inside an epoch) ==============================
+
+ if (
+ training_args.do_eval
+ and (training_args.eval_steps is not None and training_args.eval_steps > 0)
+ and cur_step % training_args.eval_steps == 0
+ ):
+ ckpt_dir = f"ckpt_epoch_{epoch + 1}_step_{cur_step}"
+ commit_msg = f"Saving weights and logs of epoch {epoch + 1} - step {cur_step}"
+ evaluate(input_rng, eval_dataset, ckpt_dir)
+ save_ckpt(ckpt_dir=ckpt_dir, commit_msg=commit_msg)
+
+ # ======================== Epoch End ==============================
+
+ # log and save info
+ if training_args.logging_steps <= 0:
+ logger.info(desc)
+
+ with open(os.path.join(training_args.output_dir, "log"), "a", encoding="UTF-8") as fp:
+ fp.write(desc + "\n")
+
+ # Save metrics
+ if has_tensorboard and jax.process_index() == 0:
+ write_metric(
+ summary_writer, train_metrics, train_time=train_time, step=cur_step, metric_key_prefix="train"
+ )
+
+ # ======================== Evaluating (after each epoch) ==============================
+
+ if training_args.do_eval and (training_args.eval_steps is None or training_args.eval_steps <= 0):
+ ckpt_dir = f"ckpt_epoch_{epoch + 1}_step_{cur_step}"
+ commit_msg = f"Saving weights and logs of epoch {epoch + 1} - step {cur_step}"
+ evaluate(input_rng, eval_dataset, ckpt_dir)
+ save_ckpt(ckpt_dir=ckpt_dir, commit_msg=commit_msg)
+
+ # ======================== Evaluating | Predicting ==============================
+
+ # Create sampling rng
+ if input_rng is None:
+ rng, input_rng = jax.random.split(rng)
+
+ # run evaluation without training
+ if training_args.do_eval and not training_args.do_train:
+ evaluate(input_rng, eval_dataset)
+
+ # run prediction after (or without) training
+ if training_args.do_predict:
+ predict(input_rng, predict_dataset)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..10a2a02f7f3af4d4fda905d30c7d6f1a01f8f043
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/README.md
@@ -0,0 +1,544 @@
+
+
+# Language model training examples
+
+The following example showcases how to train a language model from scratch
+using the JAX/Flax backend.
+
+JAX/Flax allows you to trace pure functions and compile them into efficient, fused accelerator code on both GPU and TPU.
+Models written in JAX/Flax are **immutable** and updated in a purely functional
+way which enables simple and efficient model parallelism.
+
+## Masked language modeling
+
+In the following, we demonstrate how to train a bi-directional transformer model
+using masked language modeling objective as introduced in [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805).
+More specifically, we demonstrate how JAX/Flax can be leveraged
+to pre-train [**`FacebookAI/roberta-base`**](https://huggingface.co/FacebookAI/roberta-base)
+in Norwegian on a single TPUv3-8 pod.
+
+The example script uses the 🤗 Datasets library. You can easily customize them to your needs if you need extra processing on your datasets.
+
+To setup all relevant files for training, let's create a directory.
+
+```bash
+mkdir ./norwegian-roberta-base
+```
+
+### Train tokenizer
+
+In the first step, we train a tokenizer to efficiently process the text input for the model. Similar to how it is shown in [How to train a new language model from scratch using Transformers and Tokenizers](https://huggingface.co/blog/how-to-train), we use a **`ByteLevelBPETokenizer`**.
+The tokenizer is trained on the complete Norwegian dataset of OSCAR
+and consequently saved in the cloned model directory.
+This can take up to 10 minutes depending on your hardware ☕.
+
+```python
+from datasets import load_dataset
+from tokenizers import trainers, Tokenizer, normalizers, ByteLevelBPETokenizer
+
+# load dataset
+dataset = load_dataset("oscar", "unshuffled_deduplicated_no", split="train")
+
+# Instantiate tokenizer
+tokenizer = ByteLevelBPETokenizer()
+
+def batch_iterator(batch_size=1000):
+ for i in range(0, len(dataset), batch_size):
+ yield dataset[i: i + batch_size]["text"]
+
+# Customized training
+tokenizer.train_from_iterator(batch_iterator(), vocab_size=50265, min_frequency=2, special_tokens=[
+ "",
+ "",
+ " ",
+ "",
+ "",
+])
+
+# Save files to disk
+tokenizer.save("./norwegian-roberta-base/tokenizer.json")
+```
+
+### Create configuration
+
+Next, we create the model's configuration file. This is as simple
+as loading and storing [`**FacebookAI/roberta-base**`](https://huggingface.co/FacebookAI/roberta-base)
+in the local model folder:
+
+```python
+from transformers import RobertaConfig
+
+config = RobertaConfig.from_pretrained("FacebookAI/roberta-base", vocab_size=50265)
+config.save_pretrained("./norwegian-roberta-base")
+```
+
+Great, we have set up our model repository. During training, we will automatically
+push the training logs and model weights to the repo.
+
+### Train model
+
+Next we can run the example script to pretrain the model:
+
+```bash
+python run_mlm_flax.py \
+ --output_dir="./norwegian-roberta-base" \
+ --model_type="roberta" \
+ --config_name="./norwegian-roberta-base" \
+ --tokenizer_name="./norwegian-roberta-base" \
+ --dataset_name="oscar" \
+ --dataset_config_name="unshuffled_deduplicated_no" \
+ --max_seq_length="128" \
+ --weight_decay="0.01" \
+ --per_device_train_batch_size="128" \
+ --per_device_eval_batch_size="128" \
+ --learning_rate="3e-4" \
+ --warmup_steps="1000" \
+ --overwrite_output_dir \
+ --num_train_epochs="18" \
+ --adam_beta1="0.9" \
+ --adam_beta2="0.98" \
+ --logging_steps="500" \
+ --save_steps="2500" \
+ --eval_steps="2500" \
+ --push_to_hub
+```
+
+Training should converge at a loss and accuracy
+of 1.78 and 0.64 respectively after 18 epochs on a single TPUv3-8.
+This should take less than 18 hours.
+Training statistics can be accessed on [tfhub.dev](https://tensorboard.dev/experiment/GdYmdak2TWeVz0DDRYOrrg).
+
+For a step-by-step walkthrough of how to do masked language modeling in Flax, please have a
+look at [this](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/masked_language_modeling_flax.ipynb) google colab.
+
+## Causal language modeling
+
+In the following, we demonstrate how to train an auto-regressive causal transformer model
+in JAX/Flax.
+More specifically, we pretrain a randomly initialized [**`openai-community/gpt2`**](https://huggingface.co/openai-community/gpt2) model in Norwegian on a single TPUv3-8.
+to pre-train 124M [**`openai-community/gpt2`**](https://huggingface.co/openai-community/gpt2)
+in Norwegian on a single TPUv3-8 pod.
+
+The example script uses the 🤗 Datasets library. You can easily customize them to your needs if you need extra processing on your datasets.
+
+
+To setup all relevant files for training, let's create a directory.
+
+```bash
+mkdir ./norwegian-gpt2
+```
+
+### Train tokenizer
+
+In the first step, we train a tokenizer to efficiently process the text input for the model. Similar to how it is shown in [How to train a new language model from scratch using Transformers and Tokenizers](https://huggingface.co/blog/how-to-train), we use a **`ByteLevelBPETokenizer`**.
+The tokenizer is trained on the complete Norwegian dataset of OSCAR
+and consequently saved in the cloned model directory.
+This can take up to 10 minutes depending on your hardware ☕.
+
+```python
+from datasets import load_dataset
+from tokenizers import trainers, Tokenizer, normalizers, ByteLevelBPETokenizer
+
+# load dataset
+dataset = load_dataset("oscar", "unshuffled_deduplicated_no", split="train")
+
+# Instantiate tokenizer
+tokenizer = ByteLevelBPETokenizer()
+
+def batch_iterator(batch_size=1000):
+ for i in range(0, len(dataset), batch_size):
+ yield dataset[i: i + batch_size]["text"]
+
+# Customized training
+tokenizer.train_from_iterator(batch_iterator(), vocab_size=50257, min_frequency=2, special_tokens=[
+ "",
+ "",
+ " ",
+ "",
+ "",
+])
+
+# Save files to disk
+tokenizer.save("./norwegian-gpt2/tokenizer.json")
+```
+
+### Create configuration
+
+Next, we create the model's configuration file. This is as simple
+as loading and storing [`**openai-community/gpt2**`](https://huggingface.co/openai-community/gpt2)
+in the local model folder:
+
+```python
+from transformers import GPT2Config
+
+config = GPT2Config.from_pretrained("openai-community/gpt2", resid_pdrop=0.0, embd_pdrop=0.0, attn_pdrop=0.0, vocab_size=50257)
+config.save_pretrained("./norwegian-gpt2")
+```
+
+Great, we have set up our model repository. During training, we will now automatically
+push the training logs and model weights to the repo.
+
+### Train model
+
+Finally, we can run the example script to pretrain the model:
+
+```bash
+python run_clm_flax.py \
+ --output_dir="./norwegian-gpt2" \
+ --model_type="gpt2" \
+ --config_name="./norwegian-gpt2" \
+ --tokenizer_name="./norwegian-gpt2" \
+ --dataset_name="oscar" \
+ --dataset_config_name="unshuffled_deduplicated_no" \
+ --do_train --do_eval \
+ --block_size="512" \
+ --per_device_train_batch_size="64" \
+ --per_device_eval_batch_size="64" \
+ --learning_rate="5e-3" --warmup_steps="1000" \
+ --adam_beta1="0.9" --adam_beta2="0.98" --weight_decay="0.01" \
+ --overwrite_output_dir \
+ --num_train_epochs="20" \
+ --logging_steps="500" \
+ --save_steps="2500" \
+ --eval_steps="2500" \
+ --push_to_hub
+```
+
+Training should converge at a loss and perplexity
+of 3.24 and 25.72 respectively after 20 epochs on a single TPUv3-8.
+This should take less than ~21 hours.
+Training statistics can be accessed on [tfhub.dev](https://tensorboard.dev/experiment/2zEhLwJ0Qp2FAkI3WVH9qA).
+
+For a step-by-step walkthrough of how to do causal language modeling in Flax, please have a
+look at [this](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/causal_language_modeling_flax.ipynb) google colab.
+
+## T5-like span-masked language modeling
+
+In the following, we demonstrate how to train a T5 model using the span-masked language model
+objective as proposed in the [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683).
+More specifically, we demonstrate how JAX/Flax can be leveraged
+to pre-train [**`google/t5-v1_1-base`**](https://huggingface.co/google/t5-v1_1-base)
+in Norwegian on a single TPUv3-8 pod.
+
+The example script uses the 🤗 Datasets library. You can easily customize them to your needs if you need extra processing on your datasets.
+
+Let's start by creating a model repository to save the trained model and logs.
+Here we call the model `"norwegian-t5-base"`, but you can change the model name as you like.
+
+To setup all relevant files for training, let's create a directory.
+
+```bash
+cd ./norwegian-t5-base
+```
+
+### Train tokenizer
+
+In the first step, we train a tokenizer to efficiently process the text input for the model.
+We make use of the [tokenizers](https://github.com/huggingface/tokenizers) library to train
+a sentencepiece unigram tokenizer as shown in [t5_tokenizer_model.py](https://github.com/huggingface/transformers/tree/main/examples/flax/language-modeling/t5_tokenizer_model.py)
+which is heavily inspired from [yandex-research/DeDLOC's tokenizer model](https://github.com/yandex-research/DeDLOC/blob/5c994bc64e573702a9a79add3ecd68b38f14b548/sahajbert/tokenizer/tokenizer_model.py) .
+
+The tokenizer is trained on the complete Norwegian dataset of OSCAR
+and consequently saved in the cloned model directory.
+This can take up to 120 minutes depending on your hardware ☕☕☕ .
+
+```python
+import datasets
+
+from t5_tokenizer_model import SentencePieceUnigramTokenizer
+
+
+vocab_size = 32_000
+input_sentence_size = None
+
+# Initialize a dataset
+dataset = datasets.load_dataset("oscar", name="unshuffled_deduplicated_no", split="train")
+
+tokenizer = SentencePieceUnigramTokenizer(unk_token="", eos_token="", pad_token="")
+
+
+# Build an iterator over this dataset
+def batch_iterator(input_sentence_size=None):
+ if input_sentence_size is None:
+ input_sentence_size = len(dataset)
+ batch_length = 100
+ for i in range(0, input_sentence_size, batch_length):
+ yield dataset[i: i + batch_length]["text"]
+
+
+# Train tokenizer
+tokenizer.train_from_iterator(
+ iterator=batch_iterator(input_sentence_size=input_sentence_size),
+ vocab_size=vocab_size,
+ show_progress=True,
+)
+
+# Save files to disk
+tokenizer.save("./norwegian-t5-base/tokenizer.json")
+```
+
+### Create configuration
+
+Next, we create the model's configuration file. This is as simple
+as loading and storing [`**google/t5-v1_1-base**`](https://huggingface.co/google/t5-v1_1-base)
+in the local model folder:
+
+```python
+from transformers import T5Config
+
+config = T5Config.from_pretrained("google/t5-v1_1-base", vocab_size=tokenizer.get_vocab_size())
+config.save_pretrained("./norwegian-t5-base")
+```
+
+Great, we have set up our model repository. During training, we will automatically
+push the training logs and model weights to the repo.
+
+### Train model
+
+Next we can run the example script to pretrain the model:
+
+```bash
+python run_t5_mlm_flax.py \
+ --output_dir="./norwegian-t5-base" \
+ --model_type="t5" \
+ --config_name="./norwegian-t5-base" \
+ --tokenizer_name="./norwegian-t5-base" \
+ --dataset_name="oscar" \
+ --dataset_config_name="unshuffled_deduplicated_no" \
+ --max_seq_length="512" \
+ --per_device_train_batch_size="32" \
+ --per_device_eval_batch_size="32" \
+ --adafactor \
+ --learning_rate="0.005" \
+ --weight_decay="0.001" \
+ --warmup_steps="2000" \
+ --overwrite_output_dir \
+ --logging_steps="500" \
+ --save_steps="10000" \
+ --eval_steps="2500" \
+ --push_to_hub
+```
+
+Training should converge at a loss and accuracy
+of 2.36 and 57.0 respectively after 3 epochs on a single TPUv3-8.
+This should take around 4.5 hours.
+Training statistics can be accessed on directly on the 🤗 [hub](https://huggingface.co/patrickvonplaten/t5-base-norwegian/tensorboard)
+
+## BART: Denoising language modeling
+
+In the following, we demonstrate how to train a BART model
+using denoising language modeling objective as introduced in [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://arxiv.org/abs/1910.13461).
+More specifically, we demonstrate how JAX/Flax can be leveraged
+to pre-train [**`bart-base`**](https://huggingface.co/facebook/bart-base)
+in Norwegian on a single TPUv3-8 pod.
+
+The example script uses the 🤗 Datasets library. You can easily customize them to your needs if you need extra processing on your datasets.
+
+To setup all relevant files for training, let's create a directory.
+
+```bash
+mkdir ./norwegian-bart-base
+```
+
+### Train tokenizer
+In the first step, we train a tokenizer to efficiently process the text input for the model. Similar to how it is shown in [How to train a new language model from scratch using Transformers and Tokenizers](https://huggingface.co/blog/how-to-train), we use a **`ByteLevelBPETokenizer`**.
+The tokenizer is trained on the complete Norwegian dataset of OSCAR
+and consequently saved in the cloned model directory.
+This can take up to 10 minutes depending on your hardware ☕.
+
+```python
+from datasets import load_dataset
+from tokenizers import trainers, Tokenizer, normalizers, ByteLevelBPETokenizer
+
+# load dataset
+dataset = load_dataset("oscar", "unshuffled_deduplicated_no", split="train")
+
+# Instantiate tokenizer
+tokenizer = ByteLevelBPETokenizer()
+
+def batch_iterator(batch_size=1000):
+ for i in range(0, len(dataset), batch_size):
+ yield dataset[i: i + batch_size]["text"]
+
+# Customized training
+tokenizer.train_from_iterator(batch_iterator(), vocab_size=50265, min_frequency=2, special_tokens=[
+ "",
+ "",
+ " ",
+ "",
+ "",
+])
+
+# Save files to disk
+tokenizer.save("./norwegian-bart-base/tokenizer.json")
+```
+
+### Create configuration
+
+Next, we create the model's configuration file. This is as simple
+as loading and storing [`**facebook/bart-base**`](https://huggingface.co/facebook/bart-base)
+in the local model folder:
+
+```python
+from transformers import BartConfig
+config = BartConfig.from_pretrained("facebook/bart-base", vocab_size=50265)
+config.save_pretrained("./norwegian-bart-base")
+```
+
+Great, we have set up our model repository. During training, we will automatically
+push the training logs and model weights to the repo.
+
+### Train model
+
+Next we can run the example script to pretrain the model:
+
+```bash
+python run_bart_dlm_flax.py \
+ --output_dir="./norwegian-bart-base" \
+ --config_name="./norwegian-bart-base" \
+ --tokenizer_name="./norwegian-bart-base" \
+ --dataset_name="oscar" \
+ --dataset_config_name="unshuffled_deduplicated_no" \
+ --max_seq_length="1024" \
+ --per_device_train_batch_size="32" \
+ --per_device_eval_batch_size="32" \
+ --learning_rate="1e-4" \
+ --warmup_steps="2000" \
+ --overwrite_output_dir \
+ --logging_steps="500" \
+ --save_steps="2000" \
+ --eval_steps="2000" \
+ --push_to_hub
+```
+
+Training should converge at a loss and accuracy
+of 1.36 and 0.77 respectively after 3 epochs on a single TPUv3-8.
+This should take less than 6 hours.
+Training statistics can be accessed on [tfhub.dev](https://tensorboard.dev/experiment/Maw62QlaSXWS0MOf2V2lbg/).
+
+## Runtime evaluation
+
+We also ran masked language modeling using PyTorch/XLA on a TPUv3-8, and PyTorch on 8 V100 GPUs. We report the
+overall training time below.
+For reproducibility, we state the training commands used for PyTorch/XLA and PyTorch further below.
+
+| Task | [TPU v3-8 (Flax)](https://tensorboard.dev/experiment/GdYmdak2TWeVz0DDRYOrrg/) | [TPU v3-8 (Pytorch/XLA)](https://tensorboard.dev/experiment/7Jq1kcQQRAmy12KOdXek7A/)| [8 GPU (PyTorch)](https://tensorboard.dev/experiment/PJneV8FQRxa2unPw1QnVHA) |
+|-------|-----------|------------|------------|
+| MLM | 15h32m | 23h46m | 44h14m |
+
+*All experiments are ran on Google Cloud Platform.
+GPU experiments are ran without further optimizations besides JAX
+transformations. GPU experiments are ran with full precision (fp32). "TPU v3-8"
+are 8 TPU cores on 4 chips (each chips has 2 cores), while "8 GPU" are 8 GPU chips.
+
+### Script to run MLM with PyTorch/XLA on TPUv3-8
+
+For comparison one can run the same pre-training with PyTorch/XLA on TPU. To set up PyTorch/XLA on Cloud TPU VMs, please
+refer to [this](https://cloud.google.com/tpu/docs/pytorch-xla-ug-tpu-vm) guide.
+Having created the tokenizer and configuration in `norwegian-roberta-base`, we create the following symbolic links:
+
+```bash
+ln -s ~/transformers/examples/pytorch/language-modeling/run_mlm.py ./
+ln -s ~/transformers/examples/pytorch/xla_spawn.py ./
+```
+
+, set the following environment variables:
+
+```bash
+export XRT_TPU_CONFIG="localservice;0;localhost:51011"
+unset LD_PRELOAD
+
+export NUM_TPUS=8
+export TOKENIZERS_PARALLELISM=0
+export MODEL_DIR="./norwegian-roberta-base"
+mkdir -p ${MODEL_DIR}
+```
+
+, and start training as follows:
+
+```bash
+python3 xla_spawn.py --num_cores ${NUM_TPUS} run_mlm.py --output_dir="./runs" \
+ --model_type="roberta" \
+ --config_name="${MODEL_DIR}" \
+ --tokenizer_name="${MODEL_DIR}" \
+ --dataset_name="oscar" \
+ --dataset_config_name="unshuffled_deduplicated_no" \
+ --max_seq_length="128" \
+ --weight_decay="0.01" \
+ --per_device_train_batch_size="128" \
+ --per_device_eval_batch_size="128" \
+ --learning_rate="3e-4" \
+ --warmup_steps="1000" \
+ --overwrite_output_dir \
+ --num_train_epochs="18" \
+ --adam_beta1="0.9" \
+ --adam_beta2="0.98" \
+ --do_train \
+ --do_eval \
+ --logging_steps="500" \
+ --eval_strategy="epoch" \
+ --report_to="tensorboard" \
+ --save_strategy="no"
+```
+
+### Script to compare pre-training with PyTorch on 8 GPU V100's
+
+For comparison you can run the same pre-training with PyTorch on GPU. Note that we have to make use of `gradient_accumulation`
+because the maximum batch size that fits on a single V100 GPU is 32 instead of 128.
+Having created the tokenizer and configuration in `norwegian-roberta-base`, we create the following symbolic links:
+
+```bash
+ln -s ~/transformers/examples/pytorch/language-modeling/run_mlm.py ./
+```
+
+, set some environment variables:
+
+```bash
+export NUM_GPUS=8
+export TOKENIZERS_PARALLELISM=0
+export MODEL_DIR="./norwegian-roberta-base"
+mkdir -p ${MODEL_DIR}
+```
+
+, and can start training as follows:
+
+```bash
+python3 -m torch.distributed.launch --nproc_per_node ${NUM_GPUS} run_mlm.py \
+ --output_dir="${MODEL_DIR}" \
+ --model_type="roberta" \
+ --config_name="${MODEL_DIR}" \
+ --tokenizer_name="${MODEL_DIR}" \
+ --dataset_name="oscar" \
+ --dataset_config_name="unshuffled_deduplicated_no" \
+ --max_seq_length="128" \
+ --weight_decay="0.01" \
+ --per_device_train_batch_size="32" \
+ --per_device_eval_batch_size="32" \
+ --gradient_accumulation="4" \
+ --learning_rate="3e-4" \
+ --warmup_steps="1000" \
+ --overwrite_output_dir \
+ --num_train_epochs="18" \
+ --adam_beta1="0.9" \
+ --adam_beta2="0.98" \
+ --do_train \
+ --do_eval \
+ --logging_steps="500" \
+ --eval_strategy="steps" \
+ --report_to="tensorboard" \
+ --save_strategy="no"
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..f7263bf6385b907928687640ad70d2687720aab0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/requirements.txt
@@ -0,0 +1,5 @@
+datasets >= 1.1.3
+jax>=0.2.8
+jaxlib>=0.1.59
+flax>=0.3.5
+optax>=0.0.9
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/run_bart_dlm_flax.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/run_bart_dlm_flax.py
new file mode 100644
index 0000000000000000000000000000000000000000..1f87eedd8a6aeaaba39736109c691f9f75c4add2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/run_bart_dlm_flax.py
@@ -0,0 +1,994 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Pretraining the library models for denoising language modeling on a text file or a dataset.
+Here is the full list of checkpoints on the hub that can be pretrained by this script:
+https://huggingface.co/models?filter=bart
+"""
+# You can also adapt this script on your own denoising language modeling task. Pointers for this are left as comments.
+
+import json
+import logging
+import math
+import os
+import sys
+import time
+from dataclasses import asdict, dataclass, field
+from enum import Enum
+from itertools import chain
+from pathlib import Path
+from typing import Dict, List, Optional
+
+import flax
+import jax
+import jax.numpy as jnp
+import nltk
+import numpy as np
+import optax
+from datasets import load_dataset
+from flax import jax_utils, traverse_util
+from flax.jax_utils import pad_shard_unpad
+from flax.training import train_state
+from flax.training.common_utils import get_metrics, onehot, shard
+from huggingface_hub import HfApi
+from tqdm import tqdm
+
+from transformers import (
+ CONFIG_MAPPING,
+ FLAX_MODEL_FOR_MASKED_LM_MAPPING,
+ AutoTokenizer,
+ BartConfig,
+ BatchEncoding,
+ FlaxBartForConditionalGeneration,
+ HfArgumentParser,
+ PreTrainedTokenizerBase,
+ is_tensorboard_available,
+ set_seed,
+)
+from transformers.models.bart.modeling_flax_bart import shift_tokens_right
+from transformers.utils import send_example_telemetry
+
+
+MODEL_CONFIG_CLASSES = list(FLAX_MODEL_FOR_MASKED_LM_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+@dataclass
+class TrainingArguments:
+ output_dir: str = field(
+ metadata={"help": "The output directory where the model predictions and checkpoints will be written."},
+ )
+ overwrite_output_dir: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Overwrite the content of the output directory. "
+ "Use this to continue training if output_dir points to a checkpoint directory."
+ )
+ },
+ )
+ do_train: bool = field(default=False, metadata={"help": "Whether to run training."})
+ do_eval: bool = field(default=False, metadata={"help": "Whether to run eval on the dev set."})
+ per_device_train_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for training."}
+ )
+ per_device_eval_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for evaluation."}
+ )
+ learning_rate: float = field(default=5e-5, metadata={"help": "The initial learning rate for AdamW."})
+ weight_decay: float = field(default=0.0, metadata={"help": "Weight decay for AdamW if we apply some."})
+ adam_beta1: float = field(default=0.9, metadata={"help": "Beta1 for AdamW optimizer"})
+ adam_beta2: float = field(default=0.999, metadata={"help": "Beta2 for AdamW optimizer"})
+ adam_epsilon: float = field(default=1e-8, metadata={"help": "Epsilon for AdamW optimizer."})
+ adafactor: bool = field(default=False, metadata={"help": "Whether or not to replace AdamW by Adafactor."})
+ num_train_epochs: float = field(default=3.0, metadata={"help": "Total number of training epochs to perform."})
+ warmup_steps: int = field(default=0, metadata={"help": "Linear warmup over warmup_steps."})
+ logging_steps: int = field(default=500, metadata={"help": "Log every X updates steps."})
+ save_steps: int = field(default=500, metadata={"help": "Save checkpoint every X updates steps."})
+ eval_steps: int = field(default=None, metadata={"help": "Run an evaluation every X steps."})
+ seed: int = field(default=42, metadata={"help": "Random seed that will be set at the beginning of training."})
+ push_to_hub: bool = field(
+ default=False, metadata={"help": "Whether or not to upload the trained model to the model hub after training."}
+ )
+ hub_model_id: str = field(
+ default=None, metadata={"help": "The name of the repository to keep in sync with the local `output_dir`."}
+ )
+ hub_token: str = field(default=None, metadata={"help": "The token to use to push to the Model Hub."})
+
+ def __post_init__(self):
+ if self.output_dir is not None:
+ self.output_dir = os.path.expanduser(self.output_dir)
+
+ def to_dict(self):
+ """
+ Serializes this instance while replace `Enum` by their values (for JSON serialization support). It obfuscates
+ the token values by removing their value.
+ """
+ d = asdict(self)
+ for k, v in d.items():
+ if isinstance(v, Enum):
+ d[k] = v.value
+ if isinstance(v, list) and len(v) > 0 and isinstance(v[0], Enum):
+ d[k] = [x.value for x in v]
+ if k.endswith("_token"):
+ d[k] = f"<{k.upper()}>"
+ return d
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ model_name_or_path: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
+ )
+ },
+ )
+ model_type: Optional[str] = field(
+ default=None,
+ metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ dtype: Optional[str] = field(
+ default="float32",
+ metadata={
+ "help": (
+ "Floating-point format in which the model weights should be initialized and trained. Choose one of"
+ " `[float32, float16, bfloat16]`."
+ )
+ },
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ train_ref_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input train ref data file for whole word masking in Chinese."},
+ )
+ validation_ref_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input validation ref data file for whole word masking in Chinese."},
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ validation_split_percentage: Optional[int] = field(
+ default=5,
+ metadata={
+ "help": "The percentage of the train set used as validation set in case there's no validation split"
+ },
+ )
+ max_seq_length: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization and masking. Sequences longer than this"
+ " will be truncated. Default to the max input length of the model."
+ )
+ },
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ mlm_probability: float = field(
+ default=0.3, metadata={"help": "Ratio of tokens to mask for span masked language modeling loss"}
+ )
+ permute_sentence_ratio: float = field(
+ default=1.0, metadata={"help": "Ratio of sentences to be permuted in each document"}
+ )
+ poisson_lambda: float = field(
+ default=3.0, metadata={"help": "Mean of Poisson distribution used to generate span-lengths to be masked"}
+ )
+
+ def __post_init__(self):
+ if self.dataset_name is None and self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ if extension not in ["csv", "json", "txt"]:
+ raise ValueError("train_file` should be a csv, json or text file.")
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ if extension not in ["csv", "json", "txt"]:
+ raise ValueError("`validation_file` should be a csv, json or text file.")
+
+
+@flax.struct.dataclass
+class FlaxDataCollatorForBartDenoisingLM:
+ """
+ Data collator used for BART denoising language modeling. The code is largely copied from
+ ``__.
+ For more information on how BART denoising language modeling works, one can take a look
+ at the `official paper `__
+ or the `official code for preprocessing `__ .
+ Args:
+ tokenizer (:class:`~transformers.PreTrainedTokenizer` or :class:`~transformers.PreTrainedTokenizerFast`):
+ The tokenizer used for encoding the data
+ mask_ratio (:obj:`float`):
+ The probability with which to (randomly) mask tokens in the input
+ poisson_lambda (:obj:`float`):
+ Mean parameter of Poisson distribution used to generate span-lengths to be masked
+ permute_sentence_ratio (:obj:`float`):
+ Ratio of sentences to be permuted in each document
+ decoder_start_token_id: (:obj:`int):
+ The decoder start token id of the model
+ """
+
+ tokenizer: PreTrainedTokenizerBase
+ decoder_start_token_id: int
+ mask_ratio: float = 0.3
+ poisson_lambda: float = 3.0
+ permute_sentence_ratio: float = 1.0
+
+ def __post_init__(self):
+ if self.tokenizer.mask_token is None or self.tokenizer.eos_token is None:
+ raise ValueError(
+ "This tokenizer does not have a mask token or eos token which is necessary for denoising"
+ " language modeling. "
+ )
+
+ def __call__(self, examples: List[Dict[str, List[int]]]) -> BatchEncoding:
+ # convert list to dict and tensorize input
+ batch = BatchEncoding(
+ {k: np.array([examples[i][k] for i in range(len(examples))]) for k, v in examples[0].items()}
+ )
+ batch["labels"] = batch["input_ids"].copy()
+ batch["decoder_input_ids"] = shift_tokens_right(
+ batch["labels"], self.tokenizer.pad_token_id, self.decoder_start_token_id
+ )
+ # permuting sentences
+ do_permute = False
+ if self.permute_sentence_ratio > 0.0:
+ batch["input_ids"] = self.permute_sentences(batch["input_ids"])
+ do_permute = True
+
+ # masking span of tokens (text infilling in the paper)
+ if self.mask_ratio:
+ batch["input_ids"], batch["labels"] = self.span_mask_tokens(
+ batch["input_ids"], batch["labels"], do_permute
+ )
+
+ # ignore pad tokens
+ batch["attention_mask"] = (batch["input_ids"] != self.tokenizer.pad_token_id).astype(int)
+ batch["decoder_attention_mask"] = (batch["decoder_input_ids"] != self.tokenizer.pad_token_id).astype(int)
+ return batch
+
+ def permute_sentences(self, input_ids):
+ """
+ Shuffle sentences in each document.
+ """
+ results = input_ids.copy()
+
+ # find end locations of sentences
+ end_sentence_mask = input_ids == self.tokenizer.pad_token_id
+ sentence_ends = np.argwhere(end_sentence_mask)
+ sentence_ends[:, 1] += 1
+ example_has_multiple_sentences, num_sentences = np.unique(sentence_ends[:, 0], return_counts=True)
+ num_sentences_map = dict(zip(example_has_multiple_sentences, num_sentences))
+
+ num_to_permute = np.ceil(num_sentences * self.permute_sentence_ratio).astype(int)
+ num_to_permute_map = dict(zip(example_has_multiple_sentences, num_to_permute))
+
+ sentence_ends = np.split(sentence_ends[:, 1], np.unique(sentence_ends[:, 0], return_index=True)[1][1:])
+ sentence_ends_map = dict(zip(example_has_multiple_sentences, sentence_ends))
+
+ for i in range(input_ids.shape[0]):
+ if i not in example_has_multiple_sentences:
+ continue
+ substitutions = np.random.permutation(num_sentences_map[i])[: num_to_permute_map[i]]
+ ordering = np.arange(0, num_sentences_map[i])
+ ordering[substitutions] = substitutions[np.random.permutation(num_to_permute_map[i])]
+
+ # write shuffled sentences into results
+ index = 0
+ for j in ordering:
+ sentence = input_ids[i, (sentence_ends_map[i][j - 1] if j > 0 else 0) : sentence_ends_map[i][j]]
+ results[i, index : index + sentence.shape[0]] = sentence
+ index += sentence.shape[0]
+ return results
+
+ def span_mask_tokens(self, input_ids, labels, do_permute):
+ """
+ Sampling text spans with span lengths drawn from a Poisson distribution and masking them.
+ """
+ special_tokens_mask_labels = [
+ self.tokenizer.get_special_tokens_mask(val, already_has_special_tokens=True) for val in labels.tolist()
+ ]
+ special_tokens_mask_inputs = [
+ self.tokenizer.get_special_tokens_mask(val, already_has_special_tokens=True) for val in input_ids.tolist()
+ ]
+ special_tokens_mask_labels = np.array(special_tokens_mask_labels, dtype=bool)
+ special_tokens_mask_inputs = np.array(special_tokens_mask_inputs, dtype=bool)
+
+ # determine how many tokens we need to mask in total
+ is_token_mask = ~(input_ids == self.tokenizer.pad_token_id) & ~special_tokens_mask_inputs
+ num_tokens_to_mask = int(math.ceil(is_token_mask.astype(float).sum() * self.mask_ratio))
+ if num_tokens_to_mask == 0:
+ return input_ids, labels
+
+ # generate a sufficient number of span lengths
+ span_lengths = np.random.poisson(lam=self.poisson_lambda, size=(num_tokens_to_mask,))
+ while np.cumsum(span_lengths, 0)[-1] < num_tokens_to_mask:
+ span_lengths = np.concatenate(
+ [span_lengths, np.random.poisson(lam=self.poisson_lambda, size=(num_tokens_to_mask,))]
+ )
+
+ # remove all spans of length 0
+ # note that BART inserts additional mask tokens where length == 0,
+ # which we do not implement for now as it adds additional complexity
+ span_lengths = span_lengths[span_lengths > 0]
+
+ # trim to about num_tokens_to_mask tokens
+ cutoff_idx = np.argmin(np.abs(np.cumsum(span_lengths, 0) - num_tokens_to_mask)) + 1
+ span_lengths = span_lengths[:cutoff_idx]
+
+ # randomly choose starting positions for masking
+ token_indices = np.argwhere(is_token_mask == 1)
+ span_starts = np.random.permutation(token_indices.shape[0])[: span_lengths.shape[0]]
+ # prepare mask
+ masked_indices = np.array(token_indices[span_starts])
+ mask = np.full_like(input_ids, fill_value=False)
+
+ # mask starting positions
+ for mi in masked_indices:
+ mask[tuple(mi)] = True
+ span_lengths -= 1
+
+ # fill up spans
+ max_index = input_ids.shape[1] - 1
+ remaining = (span_lengths > 0) & (masked_indices[:, 1] < max_index)
+ while np.any(remaining):
+ masked_indices[remaining, 1] += 1
+ for mi in masked_indices:
+ mask[tuple(mi)] = True
+ span_lengths -= 1
+ remaining = (span_lengths > 0) & (masked_indices[:, 1] < max_index)
+
+ # place the mask tokens
+ mask[np.where(special_tokens_mask_inputs)] = False
+ input_ids[np.where(mask)] = self.tokenizer.mask_token_id
+ if not do_permute:
+ labels[np.where(mask == 0)] = -100
+ else:
+ labels[np.where(special_tokens_mask_labels)] = -100
+
+ # remove mask tokens that are not starts of spans
+ to_remove = (mask == 1) & np.roll((mask == 1), 1, 1)
+ new_input_ids = np.full_like(input_ids, fill_value=self.tokenizer.pad_token_id)
+ for i, example in enumerate(input_ids):
+ new_example = example[~to_remove[i]]
+ new_input_ids[i, : new_example.shape[0]] = new_example
+
+ return new_input_ids, labels
+
+
+def generate_batch_splits(samples_idx: np.ndarray, batch_size: int, drop_last=True) -> np.ndarray:
+ """Generate batches of data for a specified batch size from sample indices. If the dataset size is not divisible by
+ the batch size and `drop_last` is `True`, the last incomplete batch is dropped. Else, it is returned."""
+ num_samples = len(samples_idx)
+ if drop_last:
+ samples_to_remove = num_samples % batch_size
+ if samples_to_remove != 0:
+ samples_idx = samples_idx[:-samples_to_remove]
+ sections_split = num_samples // batch_size
+ samples_idx = samples_idx.reshape((sections_split, batch_size))
+ else:
+ sections_split = math.ceil(num_samples / batch_size)
+ samples_idx = np.array_split(samples_idx, sections_split)
+ return samples_idx
+
+
+def write_train_metric(summary_writer, train_metrics, train_time, step):
+ summary_writer.scalar("train_time", train_time, step)
+
+ train_metrics = get_metrics(train_metrics)
+ for key, vals in train_metrics.items():
+ tag = f"train_{key}"
+ for i, val in enumerate(vals):
+ summary_writer.scalar(tag, val, step - len(vals) + i + 1)
+
+
+def write_eval_metric(summary_writer, eval_metrics, step):
+ for metric_name, value in eval_metrics.items():
+ summary_writer.scalar(f"eval_{metric_name}", value, step)
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_bart_dlm", model_args, data_args, framework="flax")
+
+ if (
+ os.path.exists(training_args.output_dir)
+ and os.listdir(training_args.output_dir)
+ and training_args.do_train
+ and not training_args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ level=logging.INFO,
+ datefmt="[%X]",
+ )
+
+ # Log on each process the small summary:
+ logger = logging.getLogger(__name__)
+
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Handle the repository creation
+ if training_args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = training_args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(training_args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=training_args.hub_token).repo_id
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+
+ if "validation" not in datasets.keys():
+ datasets["validation"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+ datasets["train"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ if extension == "txt":
+ extension = "text"
+ datasets = load_dataset(
+ extension,
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ )
+
+ if "validation" not in datasets.keys():
+ datasets["validation"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ )
+ datasets["train"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ )
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+
+ if model_args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ token=model_args.token,
+ )
+ elif model_args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ token=model_args.token,
+ )
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if model_args.config_name:
+ config = BartConfig.from_pretrained(
+ model_args.config_name,
+ cache_dir=model_args.cache_dir,
+ vocab_size=len(tokenizer),
+ token=model_args.token,
+ )
+ elif model_args.model_name_or_path:
+ config = BartConfig.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ else:
+ config = CONFIG_MAPPING[model_args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ if training_args.do_train:
+ column_names = datasets["train"].column_names
+ else:
+ column_names = datasets["validation"].column_names
+ text_column_name = "text" if "text" in column_names else column_names[0]
+
+ max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
+
+ # Use Punkt Sentence Tokenizer to divide a document into a list of sentences
+ nltk.download("punkt")
+ sentence_tokenizer = nltk.data.load("tokenizers/punkt/english.pickle")
+
+ def sentence_split_function(example):
+ sents = sentence_tokenizer.tokenize(example["text"])
+ # use pad token as end of sentence indicator
+ new_text = tokenizer.bos_token + f"{tokenizer.pad_token}".join(sents) + tokenizer.eos_token
+ return {"text": new_text}
+
+ split_datasets = datasets.map(
+ sentence_split_function,
+ batched=False,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ )
+
+ # Tokenize every text, then concatenate them together before splitting them in smaller parts.
+ # Since we make sure that all sequences are of the same length, no attention_mask is needed.
+ def tokenize_function(examples):
+ return tokenizer(examples[text_column_name], add_special_tokens=False, return_attention_mask=False)
+
+ tokenized_datasets = split_datasets.map(
+ tokenize_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=text_column_name,
+ load_from_cache_file=not data_args.overwrite_cache,
+ )
+
+ # Main data processing function that will concatenate all texts from our dataset and generate chunks of
+ # max_seq_length.
+ def group_texts(examples):
+ # Concatenate all texts.
+ concatenated_examples = {k: list(chain(*examples[k])) for k in examples.keys()}
+ total_length = len(concatenated_examples[list(examples.keys())[0]])
+ # We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
+ # customize this part to your needs.
+ if total_length >= max_seq_length:
+ total_length = (total_length // max_seq_length) * max_seq_length
+ # Split by chunks of max_len.
+ result = {
+ k: [t[i : i + max_seq_length] for i in range(0, total_length, max_seq_length)]
+ for k, t in concatenated_examples.items()
+ }
+ return result
+
+ # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a
+ # remainder for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value
+ # might be slower to preprocess.
+ #
+ # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
+ # https://huggingface.co/docs/datasets/process#map
+ tokenized_datasets = tokenized_datasets.map(
+ group_texts,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ )
+
+ # Enable tensorboard only on the master node
+ has_tensorboard = is_tensorboard_available()
+ if has_tensorboard and jax.process_index() == 0:
+ try:
+ from flax.metrics.tensorboard import SummaryWriter
+
+ summary_writer = SummaryWriter(log_dir=Path(training_args.output_dir))
+ except ImportError as ie:
+ has_tensorboard = False
+ logger.warning(
+ f"Unable to display metrics through TensorBoard because some package are not installed: {ie}"
+ )
+ else:
+ logger.warning(
+ "Unable to display metrics through TensorBoard because the package is not installed: "
+ "Please run pip install tensorboard to enable."
+ )
+
+ # Initialize our training
+ rng = jax.random.PRNGKey(training_args.seed)
+ dropout_rngs = jax.random.split(rng, jax.local_device_count())
+
+ if model_args.model_name_or_path:
+ model = FlaxBartForConditionalGeneration.from_pretrained(
+ model_args.model_name_or_path,
+ config=config,
+ seed=training_args.seed,
+ dtype=getattr(jnp, model_args.dtype),
+ token=model_args.token,
+ )
+ else:
+ config.vocab_size = len(tokenizer)
+ model = FlaxBartForConditionalGeneration(
+ config,
+ seed=training_args.seed,
+ dtype=getattr(jnp, model_args.dtype),
+ )
+
+ # Data collator
+ # This one will take care of randomly masking the tokens and permuting the sentences.
+ data_collator = FlaxDataCollatorForBartDenoisingLM(
+ tokenizer=tokenizer,
+ decoder_start_token_id=model.config.decoder_start_token_id,
+ mask_ratio=data_args.mlm_probability,
+ poisson_lambda=data_args.poisson_lambda,
+ permute_sentence_ratio=data_args.permute_sentence_ratio,
+ )
+
+ # Store some constant
+ num_epochs = int(training_args.num_train_epochs)
+ train_batch_size = int(training_args.per_device_train_batch_size) * jax.device_count()
+ per_device_eval_batch_size = int(training_args.per_device_eval_batch_size)
+ eval_batch_size = per_device_eval_batch_size * jax.device_count()
+
+ num_train_steps = len(tokenized_datasets["train"]) // train_batch_size * num_epochs
+
+ # Create learning rate schedule
+ warmup_fn = optax.linear_schedule(
+ init_value=0.0, end_value=training_args.learning_rate, transition_steps=training_args.warmup_steps
+ )
+ decay_fn = optax.linear_schedule(
+ init_value=training_args.learning_rate,
+ end_value=0,
+ transition_steps=num_train_steps - training_args.warmup_steps,
+ )
+ linear_decay_lr_schedule_fn = optax.join_schedules(
+ schedules=[warmup_fn, decay_fn], boundaries=[training_args.warmup_steps]
+ )
+
+ # We use Optax's "masking" functionality to not apply weight decay
+ # to bias and LayerNorm scale parameters. decay_mask_fn returns a
+ # mask boolean with the same structure as the parameters.
+ # The mask is True for parameters that should be decayed.
+ def decay_mask_fn(params):
+ flat_params = traverse_util.flatten_dict(params)
+ # find out all LayerNorm parameters
+ layer_norm_candidates = ["layernorm", "layer_norm", "ln"]
+ layer_norm_named_params = {
+ layer[-2:]
+ for layer_norm_name in layer_norm_candidates
+ for layer in flat_params.keys()
+ if layer_norm_name in "".join(layer).lower()
+ }
+ flat_mask = {path: (path[-1] != "bias" and path[-2:] not in layer_norm_named_params) for path in flat_params}
+ return traverse_util.unflatten_dict(flat_mask)
+
+ # create adam optimizer
+ if training_args.adafactor:
+ # We use the default parameters here to initialize adafactor,
+ # For more details about the parameters please check https://github.com/deepmind/optax/blob/ed02befef9bf81cbbf236be3d2b0e032e9ed4a40/optax/_src/alias.py#L74
+ optimizer = optax.adafactor(
+ learning_rate=linear_decay_lr_schedule_fn,
+ )
+ else:
+ optimizer = optax.adamw(
+ learning_rate=linear_decay_lr_schedule_fn,
+ b1=training_args.adam_beta1,
+ b2=training_args.adam_beta2,
+ weight_decay=training_args.weight_decay,
+ mask=decay_mask_fn,
+ )
+
+ # Setup train state
+ state = train_state.TrainState.create(apply_fn=model.__call__, params=model.params, tx=optimizer)
+
+ # Define gradient update step fn
+ def train_step(state, batch, dropout_rng):
+ dropout_rng, new_dropout_rng = jax.random.split(dropout_rng)
+
+ def loss_fn(params):
+ labels = batch.pop("labels")
+
+ logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
+
+ # compute loss, ignore padded input tokens and special tokens
+ label_mask = jnp.where(labels > 0, 1.0, 0.0)
+ loss = optax.softmax_cross_entropy(logits, onehot(labels, logits.shape[-1])) * label_mask
+
+ # take average
+ loss = loss.sum()
+ num_labels = label_mask.sum()
+
+ return loss, num_labels
+
+ grad_fn = jax.value_and_grad(loss_fn, has_aux=True)
+ (loss, num_labels), grad = grad_fn(state.params)
+ num_labels = jax.lax.psum(num_labels, "batch")
+
+ # true loss = total loss / total samples
+ loss = jax.lax.psum(loss, "batch")
+ loss = jax.tree_util.tree_map(lambda x: x / num_labels, loss)
+
+ # true grad = total grad / total samples
+ grad = jax.lax.psum(grad, "batch")
+ grad = jax.tree_util.tree_map(lambda x: x / num_labels, grad)
+ new_state = state.apply_gradients(grads=grad)
+
+ metrics = {"loss": loss, "learning_rate": linear_decay_lr_schedule_fn(state.step)}
+ return new_state, metrics, new_dropout_rng
+
+ # Create parallel version of the train step
+ p_train_step = jax.pmap(train_step, "batch", donate_argnums=(0,))
+
+ # Define eval fn
+ def eval_step(params, batch):
+ labels = batch.pop("labels")
+
+ logits = model(**batch, params=params, train=False)[0]
+
+ # compute loss, ignore padded input tokens and special tokens
+ label_mask = jnp.where(labels > 0, 1.0, 0.0)
+ loss = optax.softmax_cross_entropy(logits, onehot(labels, logits.shape[-1])) * label_mask
+
+ # compute accuracy
+ accuracy = jnp.equal(jnp.argmax(logits, axis=-1), labels) * label_mask
+
+ # summarize metrics
+ metrics = {"loss": loss.sum(), "accuracy": accuracy.sum(), "normalizer": label_mask.sum()}
+ metrics = jax.lax.psum(metrics, axis_name="batch")
+
+ return metrics
+
+ p_eval_step = jax.pmap(eval_step, "batch", donate_argnums=(0,))
+
+ # Replicate the train state on each device
+ state = jax_utils.replicate(state)
+
+ train_time = 0
+ epochs = tqdm(range(num_epochs), desc="Epoch ... ", position=0)
+ for epoch in epochs:
+ # ======================== Training ================================
+ train_start = time.time()
+ train_metrics = []
+
+ # Create sampling rng
+ rng, input_rng = jax.random.split(rng)
+
+ # Generate an epoch by shuffling sampling indices from the train dataset
+ num_train_samples = len(tokenized_datasets["train"])
+ # Avoid using jax.numpy here in case of TPU training
+ train_samples_idx = np.random.permutation(np.arange(num_train_samples))
+ train_batch_idx = generate_batch_splits(train_samples_idx, train_batch_size)
+
+ # Gather the indexes for creating the batch and do a training step
+ for step, batch_idx in enumerate(tqdm(train_batch_idx, desc="Training...", position=1)):
+ samples = [tokenized_datasets["train"][int(idx)] for idx in batch_idx]
+ model_inputs = data_collator(samples)
+
+ # Model forward
+ model_inputs = shard(model_inputs.data)
+ state, train_metric, dropout_rngs = p_train_step(state, model_inputs, dropout_rngs)
+ train_metrics.append(train_metric)
+
+ cur_step = epoch * (num_train_samples // train_batch_size) + step
+
+ if cur_step % training_args.logging_steps == 0 and cur_step > 0:
+ # Save metrics
+ train_metric = jax_utils.unreplicate(train_metric)
+ train_time += time.time() - train_start
+ if has_tensorboard and jax.process_index() == 0:
+ write_train_metric(summary_writer, train_metrics, train_time, cur_step)
+
+ epochs.write(
+ f"Step... ({cur_step} | Loss: {train_metric['loss']}, Learning Rate:"
+ f" {train_metric['learning_rate']})"
+ )
+
+ train_metrics = []
+
+ if cur_step % training_args.eval_steps == 0 and cur_step > 0:
+ # ======================== Evaluating ==============================
+ num_eval_samples = len(tokenized_datasets["validation"])
+ # Avoid using jax.numpy here in case of TPU training
+ eval_samples_idx = np.arange(num_eval_samples)
+ eval_batch_idx = generate_batch_splits(eval_samples_idx, eval_batch_size)
+
+ eval_metrics = []
+ for i, batch_idx in enumerate(tqdm(eval_batch_idx, desc="Evaluating ...", position=2)):
+ samples = [tokenized_datasets["validation"][int(idx)] for idx in batch_idx]
+ model_inputs = data_collator(samples)
+
+ # Model forward
+ metrics = pad_shard_unpad(p_eval_step, static_return=True)(
+ state.params, model_inputs.data, min_device_batch=per_device_eval_batch_size
+ )
+ eval_metrics.append(metrics)
+
+ # normalize eval metrics
+ eval_metrics = get_metrics(eval_metrics)
+ eval_metrics = jax.tree_util.tree_map(jnp.sum, eval_metrics)
+ eval_normalizer = eval_metrics.pop("normalizer")
+ eval_metrics = jax.tree_util.tree_map(lambda x: x / eval_normalizer, eval_metrics)
+
+ # Update progress bar
+ epochs.desc = f"Step... ({cur_step} | Loss: {eval_metrics['loss']}, Acc: {eval_metrics['accuracy']})"
+
+ # Save metrics
+ if has_tensorboard and jax.process_index() == 0:
+ write_eval_metric(summary_writer, eval_metrics, cur_step)
+
+ if cur_step % training_args.save_steps == 0 and cur_step > 0:
+ # save checkpoint after each epoch and push checkpoint to the hub
+ if jax.process_index() == 0:
+ params = jax.device_get(jax.tree_util.tree_map(lambda x: x[0], state.params))
+ model.save_pretrained(training_args.output_dir, params=params)
+ tokenizer.save_pretrained(training_args.output_dir)
+ if training_args.push_to_hub:
+ api.upload_folder(
+ commit_message=f"Saving weights and logs of step {cur_step}",
+ folder_path=training_args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=training_args.hub_token,
+ )
+
+ # Eval after training
+ if training_args.do_eval:
+ num_eval_samples = len(tokenized_datasets["validation"])
+ # Avoid using jax.numpy here in case of TPU training
+ eval_samples_idx = np.arange(num_eval_samples)
+ eval_batch_idx = generate_batch_splits(eval_samples_idx, eval_batch_size)
+
+ eval_metrics = []
+ for _, batch_idx in enumerate(tqdm(eval_batch_idx, desc="Evaluating ...", position=2)):
+ samples = [tokenized_datasets["validation"][int(idx)] for idx in batch_idx]
+ model_inputs = data_collator(samples)
+
+ # Model forward
+ metrics = pad_shard_unpad(p_eval_step, static_return=True)(
+ state.params, model_inputs.data, min_device_batch=per_device_eval_batch_size
+ )
+ eval_metrics.append(metrics)
+
+ # normalize eval metrics
+ eval_metrics = get_metrics(eval_metrics)
+ eval_metrics = jax.tree_util.tree_map(lambda metric: jnp.sum(metric).item(), eval_metrics)
+ eval_normalizer = eval_metrics.pop("normalizer")
+ eval_metrics = jax.tree_util.tree_map(lambda x: x / eval_normalizer, eval_metrics)
+
+ try:
+ perplexity = math.exp(eval_metrics["loss"])
+ except OverflowError:
+ perplexity = float("inf")
+ eval_metrics["perplexity"] = perplexity
+
+ if jax.process_index() == 0:
+ eval_metrics = {f"eval_{metric_name}": value for metric_name, value in eval_metrics.items()}
+ path = os.path.join(training_args.output_dir, "eval_results.json")
+ with open(path, "w") as f:
+ json.dump(eval_metrics, f, indent=4, sort_keys=True)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/run_clm_flax.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/run_clm_flax.py
new file mode 100644
index 0000000000000000000000000000000000000000..c486aae71f62276e03bc7c3aca019d8d807b698a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/run_clm_flax.py
@@ -0,0 +1,870 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Pre-training/Fine-tuning the library models for causal language modeling (GPT, GPT-2, CTRL, ...) on a text file or a dataset.
+
+Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
+https://huggingface.co/models?filter=text-generation
+"""
+# You can also adapt this script on your own causal language modeling task. Pointers for this are left as comments.
+
+import json
+import logging
+import math
+import os
+import sys
+import time
+from dataclasses import asdict, dataclass, field
+from enum import Enum
+from itertools import chain
+from pathlib import Path
+from typing import Callable, Optional
+
+import datasets
+import jax
+import jax.numpy as jnp
+import numpy as np
+import optax
+from datasets import Dataset, load_dataset
+from flax import jax_utils, traverse_util
+from flax.jax_utils import pad_shard_unpad, unreplicate
+from flax.training import train_state
+from flax.training.common_utils import get_metrics, onehot, shard, shard_prng_key
+from huggingface_hub import HfApi
+from tqdm import tqdm
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ FLAX_MODEL_FOR_CAUSAL_LM_MAPPING,
+ AutoConfig,
+ AutoTokenizer,
+ FlaxAutoModelForCausalLM,
+ HfArgumentParser,
+ is_tensorboard_available,
+ set_seed,
+)
+from transformers.testing_utils import CaptureLogger
+from transformers.utils import send_example_telemetry
+
+
+logger = logging.getLogger(__name__)
+
+MODEL_CONFIG_CLASSES = list(FLAX_MODEL_FOR_CAUSAL_LM_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+@dataclass
+class TrainingArguments:
+ output_dir: str = field(
+ metadata={"help": "The output directory where the model predictions and checkpoints will be written."},
+ )
+ overwrite_output_dir: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Overwrite the content of the output directory. "
+ "Use this to continue training if output_dir points to a checkpoint directory."
+ )
+ },
+ )
+ do_train: bool = field(default=False, metadata={"help": "Whether to run training."})
+ do_eval: bool = field(default=False, metadata={"help": "Whether to run eval on the dev set."})
+ per_device_train_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for training."}
+ )
+ per_device_eval_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for evaluation."}
+ )
+ learning_rate: float = field(default=5e-5, metadata={"help": "The initial learning rate for AdamW."})
+ weight_decay: float = field(default=0.0, metadata={"help": "Weight decay for AdamW if we apply some."})
+ adam_beta1: float = field(default=0.9, metadata={"help": "Beta1 for AdamW optimizer"})
+ adam_beta2: float = field(default=0.999, metadata={"help": "Beta2 for AdamW optimizer"})
+ adam_epsilon: float = field(default=1e-8, metadata={"help": "Epsilon for AdamW optimizer."})
+ adafactor: bool = field(default=False, metadata={"help": "Whether or not to replace AdamW by Adafactor."})
+ num_train_epochs: float = field(default=3.0, metadata={"help": "Total number of training epochs to perform."})
+ warmup_steps: int = field(default=0, metadata={"help": "Linear warmup over warmup_steps."})
+ logging_steps: int = field(default=500, metadata={"help": "Log every X updates steps."})
+ save_steps: int = field(default=500, metadata={"help": "Save checkpoint every X updates steps."})
+ eval_steps: int = field(default=None, metadata={"help": "Run an evaluation every X steps."})
+ seed: int = field(default=42, metadata={"help": "Random seed that will be set at the beginning of training."})
+ push_to_hub: bool = field(
+ default=False, metadata={"help": "Whether or not to upload the trained model to the model hub after training."}
+ )
+ hub_model_id: str = field(
+ default=None, metadata={"help": "The name of the repository to keep in sync with the local `output_dir`."}
+ )
+ hub_token: str = field(default=None, metadata={"help": "The token to use to push to the Model Hub."})
+
+ def __post_init__(self):
+ if self.output_dir is not None:
+ self.output_dir = os.path.expanduser(self.output_dir)
+
+ def to_dict(self):
+ """
+ Serializes this instance while replace `Enum` by their values (for JSON serialization support). It obfuscates
+ the token values by removing their value.
+ """
+ d = asdict(self)
+ for k, v in d.items():
+ if isinstance(v, Enum):
+ d[k] = v.value
+ if isinstance(v, list) and len(v) > 0 and isinstance(v[0], Enum):
+ d[k] = [x.value for x in v]
+ if k.endswith("_token"):
+ d[k] = f"<{k.upper()}>"
+ return d
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ model_name_or_path: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
+ )
+ },
+ )
+ model_type: Optional[str] = field(
+ default=None,
+ metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ dtype: Optional[str] = field(
+ default="float32",
+ metadata={
+ "help": (
+ "Floating-point format in which the model weights should be initialized and trained. Choose one of"
+ " `[float32, float16, bfloat16]`."
+ )
+ },
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ validation_split_percentage: Optional[int] = field(
+ default=5,
+ metadata={
+ "help": "The percentage of the train set used as validation set in case there's no validation split"
+ },
+ )
+ block_size: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Optional input sequence length after tokenization. "
+ "The training dataset will be truncated in block of this size for training. "
+ "Default to the model max input length for single sentence inputs (take into account special tokens)."
+ )
+ },
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ keep_linebreaks: bool = field(
+ default=True, metadata={"help": "Whether to keep line breaks when using TXT files or not."}
+ )
+
+ def __post_init__(self):
+ if self.dataset_name is None and self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ if extension not in ["csv", "json", "txt"]:
+ raise ValueError("train_file` should be a csv, json or text file.")
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ if extension not in ["csv", "json", "txt"]:
+ raise ValueError("`validation_file` should be a csv, json or text file.")
+
+
+class TrainState(train_state.TrainState):
+ dropout_rng: jnp.ndarray
+
+ def replicate(self):
+ return jax_utils.replicate(self).replace(dropout_rng=shard_prng_key(self.dropout_rng))
+
+
+def data_loader(rng: jax.random.PRNGKey, dataset: Dataset, batch_size: int, shuffle: bool = False, drop_last=True):
+ """
+ Returns batches of size `batch_size` from `dataset`. If `drop_last` is set to `False`, the final batch may be incomplete,
+ and range in size from 1 to `batch_size`. Shuffle batches if `shuffle` is `True`.
+ """
+ if shuffle:
+ batch_idx = jax.random.permutation(rng, len(dataset))
+ batch_idx = np.asarray(batch_idx)
+ else:
+ batch_idx = np.arange(len(dataset))
+
+ if drop_last:
+ steps_per_epoch = len(dataset) // batch_size
+ batch_idx = batch_idx[: steps_per_epoch * batch_size] # Skip incomplete batch.
+ batch_idx = batch_idx.reshape((steps_per_epoch, batch_size))
+ else:
+ steps_per_epoch = math.ceil(len(dataset) / batch_size)
+ batch_idx = np.array_split(batch_idx, steps_per_epoch)
+
+ for idx in batch_idx:
+ batch = dataset[idx]
+ batch = {k: np.array(v) for k, v in batch.items()}
+
+ yield batch
+
+
+def write_train_metric(summary_writer, train_metrics, train_time, step):
+ summary_writer.scalar("train_time", train_time, step)
+
+ train_metrics = get_metrics(train_metrics)
+ for key, vals in train_metrics.items():
+ tag = f"train_{key}"
+ for i, val in enumerate(vals):
+ summary_writer.scalar(tag, val, step - len(vals) + i + 1)
+
+
+def write_eval_metric(summary_writer, eval_metrics, step):
+ for metric_name, value in eval_metrics.items():
+ summary_writer.scalar(f"eval_{metric_name}", value, step)
+
+
+def create_learning_rate_fn(
+ train_ds_size: int, train_batch_size: int, num_train_epochs: int, num_warmup_steps: int, learning_rate: float
+) -> Callable[[int], jnp.ndarray]:
+ """Returns a linear warmup, linear_decay learning rate function."""
+ steps_per_epoch = train_ds_size // train_batch_size
+ num_train_steps = steps_per_epoch * num_train_epochs
+ warmup_fn = optax.linear_schedule(init_value=0.0, end_value=learning_rate, transition_steps=num_warmup_steps)
+ decay_fn = optax.linear_schedule(
+ init_value=learning_rate, end_value=0, transition_steps=num_train_steps - num_warmup_steps
+ )
+ schedule_fn = optax.join_schedules(schedules=[warmup_fn, decay_fn], boundaries=[num_warmup_steps])
+ return schedule_fn
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_clm", model_args, data_args, framework="flax")
+
+ if (
+ os.path.exists(training_args.output_dir)
+ and os.listdir(training_args.output_dir)
+ and training_args.do_train
+ and not training_args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ # Setup logging, we only want one process per machine to log things on the screen.
+ logger.setLevel(logging.INFO if jax.process_index() == 0 else logging.ERROR)
+ if jax.process_index() == 0:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Handle the repository creation
+ if training_args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = training_args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(training_args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=training_args.hub_token).repo_id
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantees that only one local process can concurrently
+ # download the dataset.
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ dataset = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ keep_in_memory=False,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ if "validation" not in dataset.keys():
+ dataset["validation"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ dataset["train"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ dataset_args = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ if extension == "txt":
+ extension = "text"
+ dataset_args["keep_linebreaks"] = data_args.keep_linebreaks
+ dataset = load_dataset(
+ extension,
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ **dataset_args,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ )
+
+ if "validation" not in dataset.keys():
+ dataset["validation"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ **dataset_args,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ )
+ dataset["train"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ **dataset_args,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ )
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ if model_args.config_name:
+ config = AutoConfig.from_pretrained(
+ model_args.config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ elif model_args.model_name_or_path:
+ config = AutoConfig.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ config = CONFIG_MAPPING[model_args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ if model_args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ elif model_args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if model_args.model_name_or_path:
+ model = FlaxAutoModelForCausalLM.from_pretrained(
+ model_args.model_name_or_path,
+ config=config,
+ seed=training_args.seed,
+ dtype=getattr(jnp, model_args.dtype),
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ model = FlaxAutoModelForCausalLM.from_config(
+ config,
+ seed=training_args.seed,
+ dtype=getattr(jnp, model_args.dtype),
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ if training_args.do_train:
+ column_names = dataset["train"].column_names
+ else:
+ column_names = dataset["validation"].column_names
+ text_column_name = "text" if "text" in column_names else column_names[0]
+
+ # since this will be pickled to avoid _LazyModule error in Hasher force logger loading before tokenize_function
+ tok_logger = transformers.utils.logging.get_logger("transformers.tokenization_utils_base")
+
+ def tokenize_function(examples):
+ with CaptureLogger(tok_logger) as cl:
+ output = tokenizer(examples[text_column_name])
+ # clm input could be much much longer than block_size
+ if "Token indices sequence length is longer than the" in cl.out:
+ tok_logger.warning(
+ "^^^^^^^^^^^^^^^^ Please ignore the warning above - this long input will be chunked into smaller bits"
+ " before being passed to the model."
+ )
+ return output
+
+ tokenized_datasets = dataset.map(
+ tokenize_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ )
+
+ if data_args.block_size is None:
+ block_size = tokenizer.model_max_length
+ if block_size > config.max_position_embeddings:
+ logger.warning(
+ f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
+ f"Using block_size={min(1024, config.max_position_embeddings)} instead. You can change that default value by passing --block_size xxx."
+ )
+ block_size = min(1024, config.max_position_embeddings)
+ else:
+ if data_args.block_size > tokenizer.model_max_length:
+ logger.warning(
+ f"The block_size passed ({data_args.block_size}) is larger than the maximum length for the model "
+ f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
+ )
+ block_size = min(data_args.block_size, tokenizer.model_max_length)
+
+ # Main data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
+ def group_texts(examples):
+ # Concatenate all texts.
+ concatenated_examples = {k: list(chain(*examples[k])) for k in examples.keys()}
+ total_length = len(concatenated_examples[list(examples.keys())[0]])
+ # We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
+ # customize this part to your needs.
+ if total_length >= block_size:
+ total_length = (total_length // block_size) * block_size
+ # Split by chunks of max_len.
+ result = {
+ k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
+ for k, t in concatenated_examples.items()
+ }
+ result["labels"] = result["input_ids"].copy()
+ return result
+
+ # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
+ # for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
+ # to preprocess.
+ #
+ # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
+ # https://huggingface.co/docs/datasets/process#map
+
+ lm_datasets = tokenized_datasets.map(
+ group_texts,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ )
+
+ if training_args.do_train:
+ if "train" not in tokenized_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = lm_datasets["train"]
+ if data_args.max_train_samples is not None:
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+
+ if training_args.do_eval:
+ if "validation" not in tokenized_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_dataset = lm_datasets["validation"]
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+
+ # Enable tensorboard only on the master node
+ has_tensorboard = is_tensorboard_available()
+ if has_tensorboard and jax.process_index() == 0:
+ try:
+ from flax.metrics.tensorboard import SummaryWriter
+
+ summary_writer = SummaryWriter(log_dir=Path(training_args.output_dir))
+ except ImportError as ie:
+ has_tensorboard = False
+ logger.warning(
+ f"Unable to display metrics through TensorBoard because some package are not installed: {ie}"
+ )
+ else:
+ logger.warning(
+ "Unable to display metrics through TensorBoard because the package is not installed: "
+ "Please run pip install tensorboard to enable."
+ )
+
+ # Initialize our training
+ rng = jax.random.PRNGKey(training_args.seed)
+ rng, dropout_rng = jax.random.split(rng)
+
+ # Store some constant
+ num_epochs = int(training_args.num_train_epochs)
+ train_batch_size = int(training_args.per_device_train_batch_size) * jax.device_count()
+ per_device_eval_batch_size = int(training_args.per_device_eval_batch_size)
+ eval_batch_size = per_device_eval_batch_size * jax.device_count()
+ steps_per_epoch = len(train_dataset) // train_batch_size
+ total_train_steps = steps_per_epoch * num_epochs
+
+ # Create learning rate schedule
+ linear_decay_lr_schedule_fn = create_learning_rate_fn(
+ len(train_dataset),
+ train_batch_size,
+ training_args.num_train_epochs,
+ training_args.warmup_steps,
+ training_args.learning_rate,
+ )
+
+ # We use Optax's "masking" functionality to not apply weight decay
+ # to bias and LayerNorm scale parameters. decay_mask_fn returns a
+ # mask boolean with the same structure as the parameters.
+ # The mask is True for parameters that should be decayed.
+ def decay_mask_fn(params):
+ flat_params = traverse_util.flatten_dict(params)
+ # find out all LayerNorm parameters
+ layer_norm_candidates = ["layernorm", "layer_norm", "ln"]
+ layer_norm_named_params = {
+ layer[-2:]
+ for layer_norm_name in layer_norm_candidates
+ for layer in flat_params.keys()
+ if layer_norm_name in "".join(layer).lower()
+ }
+ flat_mask = {path: (path[-1] != "bias" and path[-2:] not in layer_norm_named_params) for path in flat_params}
+ return traverse_util.unflatten_dict(flat_mask)
+
+ # create adam optimizer
+ if training_args.adafactor:
+ # We use the default parameters here to initialize adafactor,
+ # For more details about the parameters please check https://github.com/deepmind/optax/blob/ed02befef9bf81cbbf236be3d2b0e032e9ed4a40/optax/_src/alias.py#L74
+ optimizer = optax.adafactor(
+ learning_rate=linear_decay_lr_schedule_fn,
+ )
+ else:
+ optimizer = optax.adamw(
+ learning_rate=linear_decay_lr_schedule_fn,
+ b1=training_args.adam_beta1,
+ b2=training_args.adam_beta2,
+ eps=training_args.adam_epsilon,
+ weight_decay=training_args.weight_decay,
+ mask=decay_mask_fn,
+ )
+
+ # Setup train state
+ state = TrainState.create(apply_fn=model.__call__, params=model.params, tx=optimizer, dropout_rng=dropout_rng)
+
+ def loss_fn(logits, labels):
+ shift_logits = logits[..., :-1, :]
+ shift_labels = labels[..., 1:]
+ loss = optax.softmax_cross_entropy(shift_logits, onehot(shift_labels, shift_logits.shape[-1]))
+ return loss.mean()
+
+ # Define gradient update step fn
+ def train_step(state, batch):
+ dropout_rng, new_dropout_rng = jax.random.split(state.dropout_rng)
+
+ def compute_loss(params):
+ labels = batch.pop("labels")
+ logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
+ loss = loss_fn(logits, labels)
+ return loss
+
+ grad_fn = jax.value_and_grad(compute_loss)
+ loss, grad = grad_fn(state.params)
+ grad = jax.lax.pmean(grad, "batch")
+
+ new_state = state.apply_gradients(grads=grad, dropout_rng=new_dropout_rng)
+
+ metrics = {"loss": loss, "learning_rate": linear_decay_lr_schedule_fn(state.step)}
+ metrics = jax.lax.pmean(metrics, axis_name="batch")
+
+ return new_state, metrics
+
+ # Define eval fn
+ def eval_step(params, batch):
+ labels = batch.pop("labels")
+ logits = model(**batch, params=params, train=False)[0]
+ loss = loss_fn(logits, labels)
+
+ # summarize metrics
+ metrics = {"loss": loss}
+ metrics = jax.lax.pmean(metrics, axis_name="batch")
+ return metrics
+
+ # Create parallel version of the train and eval step
+ p_train_step = jax.pmap(train_step, "batch", donate_argnums=(0,))
+ p_eval_step = jax.pmap(eval_step, "batch")
+
+ # Replicate the train state on each device
+ state = state.replicate()
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {num_epochs}")
+ logger.info(f" Instantaneous batch size per device = {training_args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel & distributed) = {train_batch_size}")
+ logger.info(f" Total optimization steps = {total_train_steps}")
+
+ train_time = 0
+ train_metrics = []
+ epochs = tqdm(range(num_epochs), desc="Epoch ... ", position=0)
+ for epoch in epochs:
+ # ======================== Training ================================
+ train_start = time.time()
+
+ # Create sampling rng
+ rng, input_rng = jax.random.split(rng)
+
+ # Generate an epoch by shuffling sampling indices from the train dataset
+ train_loader = data_loader(input_rng, train_dataset, train_batch_size, shuffle=True)
+ steps_per_epoch = len(train_dataset) // train_batch_size
+ # train
+ for step in tqdm(range(steps_per_epoch), desc="Training...", position=1, leave=False):
+ batch = next(train_loader)
+ batch = shard(batch)
+ state, train_metric = p_train_step(state, batch)
+ train_metrics.append(train_metric)
+
+ cur_step = epoch * (len(train_dataset) // train_batch_size) + step
+
+ if cur_step % training_args.logging_steps == 0 and cur_step > 0:
+ # Save metrics
+ train_metric = unreplicate(train_metric)
+ train_time += time.time() - train_start
+ if has_tensorboard and jax.process_index() == 0:
+ write_train_metric(summary_writer, train_metrics, train_time, cur_step)
+
+ epochs.write(
+ f"Step... ({cur_step} | Loss: {train_metric['loss'].mean()}, Learning Rate:"
+ f" {train_metric['learning_rate'].mean()})"
+ )
+
+ train_metrics = []
+
+ if cur_step % training_args.eval_steps == 0 and cur_step > 0:
+ # ======================== Evaluating ==============================
+ eval_metrics = []
+ eval_loader = data_loader(input_rng, eval_dataset, eval_batch_size, drop_last=False)
+ eval_steps = math.ceil(len(eval_dataset) / eval_batch_size)
+ for _ in tqdm(range(eval_steps), desc="Evaluating...", position=2, leave=False):
+ # Model forward
+ batch = next(eval_loader)
+ metrics = pad_shard_unpad(p_eval_step, static_return=True)(
+ state.params, batch, min_device_batch=per_device_eval_batch_size
+ )
+ eval_metrics.append(metrics)
+
+ # normalize eval metrics
+ eval_metrics = get_metrics(eval_metrics)
+ eval_metrics = jax.tree_util.tree_map(jnp.mean, eval_metrics)
+
+ try:
+ eval_metrics["perplexity"] = math.exp(eval_metrics["loss"])
+ except OverflowError:
+ eval_metrics["perplexity"] = float("inf")
+
+ # Print metrics and update progress bar
+ desc = (
+ f"Step... ({cur_step} | Eval Loss: {eval_metrics['loss']} | Eval Perplexity:"
+ f" {eval_metrics['perplexity']})"
+ )
+ epochs.write(desc)
+ epochs.desc = desc
+
+ # Save metrics
+ if has_tensorboard and jax.process_index() == 0:
+ write_eval_metric(summary_writer, eval_metrics, cur_step)
+
+ if cur_step % training_args.save_steps == 0 and cur_step > 0:
+ # save checkpoint after each epoch and push checkpoint to the hub
+ if jax.process_index() == 0:
+ params = jax.device_get(unreplicate(state.params))
+ model.save_pretrained(training_args.output_dir, params=params)
+ tokenizer.save_pretrained(training_args.output_dir)
+ if training_args.push_to_hub:
+ api.upload_folder(
+ commit_message=f"Saving weights and logs of step {cur_step}",
+ folder_path=training_args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=training_args.hub_token,
+ )
+ # Eval after training
+ if training_args.do_eval:
+ eval_metrics = []
+ eval_loader = data_loader(input_rng, eval_dataset, eval_batch_size, drop_last=False)
+ eval_steps = math.ceil(len(eval_dataset) / eval_batch_size)
+ for _ in tqdm(range(eval_steps), desc="Evaluating...", position=2, leave=False):
+ # Model forward
+ batch = next(eval_loader)
+ metrics = pad_shard_unpad(p_eval_step, static_return=True)(
+ state.params, batch, min_device_batch=per_device_eval_batch_size
+ )
+ eval_metrics.append(metrics)
+
+ # normalize eval metrics
+ eval_metrics = get_metrics(eval_metrics)
+ eval_metrics = jax.tree_util.tree_map(lambda x: jnp.mean(x).item(), eval_metrics)
+
+ try:
+ eval_metrics["perplexity"] = math.exp(eval_metrics["loss"])
+ except OverflowError:
+ eval_metrics["perplexity"] = float("inf")
+
+ if jax.process_index() == 0:
+ eval_metrics = {f"eval_{metric_name}": value for metric_name, value in eval_metrics.items()}
+ path = os.path.join(training_args.output_dir, "eval_results.json")
+ with open(path, "w") as f:
+ json.dump(eval_metrics, f, indent=4, sort_keys=True)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/run_mlm_flax.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/run_mlm_flax.py
new file mode 100644
index 0000000000000000000000000000000000000000..4d837e9c113c3b6a195b050d3e83763982b7ed78
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/run_mlm_flax.py
@@ -0,0 +1,925 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for masked language modeling (BERT, ALBERT, RoBERTa...) with whole word masking on a
+text file or a dataset.
+
+Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
+https://huggingface.co/models?filter=fill-mask
+"""
+
+import json
+import logging
+import math
+import os
+import sys
+import time
+from dataclasses import asdict, dataclass, field
+from enum import Enum
+from itertools import chain
+
+# You can also adapt this script on your own masked language modeling task. Pointers for this are left as comments.
+from pathlib import Path
+from typing import Dict, List, Optional, Tuple
+
+import flax
+import jax
+import jax.numpy as jnp
+import numpy as np
+import optax
+from datasets import load_dataset
+from flax import jax_utils, traverse_util
+from flax.jax_utils import pad_shard_unpad
+from flax.training import train_state
+from flax.training.common_utils import get_metrics, onehot, shard
+from huggingface_hub import HfApi
+from tqdm import tqdm
+
+from transformers import (
+ CONFIG_MAPPING,
+ FLAX_MODEL_FOR_MASKED_LM_MAPPING,
+ AutoConfig,
+ AutoTokenizer,
+ FlaxAutoModelForMaskedLM,
+ HfArgumentParser,
+ PreTrainedTokenizerBase,
+ TensorType,
+ is_tensorboard_available,
+ set_seed,
+)
+from transformers.utils import send_example_telemetry
+
+
+MODEL_CONFIG_CLASSES = list(FLAX_MODEL_FOR_MASKED_LM_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+@dataclass
+class TrainingArguments:
+ output_dir: str = field(
+ metadata={"help": "The output directory where the model predictions and checkpoints will be written."},
+ )
+ overwrite_output_dir: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Overwrite the content of the output directory. "
+ "Use this to continue training if output_dir points to a checkpoint directory."
+ )
+ },
+ )
+ do_train: bool = field(default=False, metadata={"help": "Whether to run training."})
+ do_eval: bool = field(default=False, metadata={"help": "Whether to run eval on the dev set."})
+ per_device_train_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for training."}
+ )
+ per_device_eval_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for evaluation."}
+ )
+ learning_rate: float = field(default=5e-5, metadata={"help": "The initial learning rate for AdamW."})
+ weight_decay: float = field(default=0.0, metadata={"help": "Weight decay for AdamW if we apply some."})
+ adam_beta1: float = field(default=0.9, metadata={"help": "Beta1 for AdamW optimizer"})
+ adam_beta2: float = field(default=0.999, metadata={"help": "Beta2 for AdamW optimizer"})
+ adam_epsilon: float = field(default=1e-8, metadata={"help": "Epsilon for AdamW optimizer."})
+ adafactor: bool = field(default=False, metadata={"help": "Whether or not to replace AdamW by Adafactor."})
+ num_train_epochs: float = field(default=3.0, metadata={"help": "Total number of training epochs to perform."})
+ warmup_steps: int = field(default=0, metadata={"help": "Linear warmup over warmup_steps."})
+ logging_steps: int = field(default=500, metadata={"help": "Log every X updates steps."})
+ save_steps: int = field(default=500, metadata={"help": "Save checkpoint every X updates steps."})
+ eval_steps: int = field(default=None, metadata={"help": "Run an evaluation every X steps."})
+ seed: int = field(default=42, metadata={"help": "Random seed that will be set at the beginning of training."})
+ push_to_hub: bool = field(
+ default=False, metadata={"help": "Whether or not to upload the trained model to the model hub after training."}
+ )
+ hub_model_id: str = field(
+ default=None, metadata={"help": "The name of the repository to keep in sync with the local `output_dir`."}
+ )
+ hub_token: str = field(default=None, metadata={"help": "The token to use to push to the Model Hub."})
+ gradient_checkpointing: bool = field(
+ default=False,
+ metadata={
+ "help": "If True, use gradient checkpointing to save memory at the expense of slower backward pass."
+ },
+ )
+
+ def __post_init__(self):
+ if self.output_dir is not None:
+ self.output_dir = os.path.expanduser(self.output_dir)
+
+ def to_dict(self):
+ """
+ Serializes this instance while replace `Enum` by their values (for JSON serialization support). It obfuscates
+ the token values by removing their value.
+ """
+ d = asdict(self)
+ for k, v in d.items():
+ if isinstance(v, Enum):
+ d[k] = v.value
+ if isinstance(v, list) and len(v) > 0 and isinstance(v[0], Enum):
+ d[k] = [x.value for x in v]
+ if k.endswith("_token"):
+ d[k] = f"<{k.upper()}>"
+ return d
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ model_name_or_path: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
+ )
+ },
+ )
+ model_type: Optional[str] = field(
+ default=None,
+ metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ dtype: Optional[str] = field(
+ default="float32",
+ metadata={
+ "help": (
+ "Floating-point format in which the model weights should be initialized and trained. Choose one of"
+ " `[float32, float16, bfloat16]`."
+ )
+ },
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ train_ref_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input train ref data file for whole word masking in Chinese."},
+ )
+ validation_ref_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input validation ref data file for whole word masking in Chinese."},
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ validation_split_percentage: Optional[int] = field(
+ default=5,
+ metadata={
+ "help": "The percentage of the train set used as validation set in case there's no validation split"
+ },
+ )
+ max_seq_length: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated. Default to the max input length of the model."
+ )
+ },
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ mlm_probability: float = field(
+ default=0.15, metadata={"help": "Ratio of tokens to mask for masked language modeling loss"}
+ )
+ pad_to_max_length: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to pad all samples to `max_seq_length`. "
+ "If False, will pad the samples dynamically when batching to the maximum length in the batch."
+ )
+ },
+ )
+ line_by_line: bool = field(
+ default=False,
+ metadata={"help": "Whether distinct lines of text in the dataset are to be handled as distinct sequences."},
+ )
+
+ def __post_init__(self):
+ if self.dataset_name is None and self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, a json or a txt file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, a json or a txt file."
+
+
+@flax.struct.dataclass
+class FlaxDataCollatorForLanguageModeling:
+ """
+ Data collator used for language modeling. Inputs are dynamically padded to the maximum length of a batch if they
+ are not all of the same length.
+
+ Args:
+ tokenizer (:class:`~transformers.PreTrainedTokenizer` or :class:`~transformers.PreTrainedTokenizerFast`):
+ The tokenizer used for encoding the data.
+ mlm_probability (:obj:`float`, `optional`, defaults to 0.15):
+ The probability with which to (randomly) mask tokens in the input.
+
+ .. note::
+
+ For best performance, this data collator should be used with a dataset having items that are dictionaries or
+ BatchEncoding, with the :obj:`"special_tokens_mask"` key, as returned by a
+ :class:`~transformers.PreTrainedTokenizer` or a :class:`~transformers.PreTrainedTokenizerFast` with the
+ argument :obj:`return_special_tokens_mask=True`.
+ """
+
+ tokenizer: PreTrainedTokenizerBase
+ mlm_probability: float = 0.15
+
+ def __post_init__(self):
+ if self.tokenizer.mask_token is None:
+ raise ValueError(
+ "This tokenizer does not have a mask token which is necessary for masked language modeling. "
+ "You should pass `mlm=False` to train on causal language modeling instead."
+ )
+
+ def __call__(self, examples: List[Dict[str, np.ndarray]], pad_to_multiple_of: int) -> Dict[str, np.ndarray]:
+ # Handle dict or lists with proper padding and conversion to tensor.
+ batch = self.tokenizer.pad(examples, pad_to_multiple_of=pad_to_multiple_of, return_tensors=TensorType.NUMPY)
+
+ # If special token mask has been preprocessed, pop it from the dict.
+ special_tokens_mask = batch.pop("special_tokens_mask", None)
+
+ batch["input_ids"], batch["labels"] = self.mask_tokens(
+ batch["input_ids"], special_tokens_mask=special_tokens_mask
+ )
+ return batch
+
+ def mask_tokens(
+ self, inputs: np.ndarray, special_tokens_mask: Optional[np.ndarray]
+ ) -> Tuple[np.ndarray, np.ndarray]:
+ """
+ Prepare masked tokens inputs/labels for masked language modeling: 80% MASK, 10% random, 10% original.
+ """
+ labels = inputs.copy()
+ # We sample a few tokens in each sequence for MLM training (with probability `self.mlm_probability`)
+ probability_matrix = np.full(labels.shape, self.mlm_probability)
+ special_tokens_mask = special_tokens_mask.astype("bool")
+
+ probability_matrix[special_tokens_mask] = 0.0
+ masked_indices = np.random.binomial(1, probability_matrix).astype("bool")
+ labels[~masked_indices] = -100 # We only compute loss on masked tokens
+
+ # 80% of the time, we replace masked input tokens with tokenizer.mask_token ([MASK])
+ indices_replaced = np.random.binomial(1, np.full(labels.shape, 0.8)).astype("bool") & masked_indices
+ inputs[indices_replaced] = self.tokenizer.convert_tokens_to_ids(self.tokenizer.mask_token)
+
+ # 10% of the time, we replace masked input tokens with random word
+ indices_random = np.random.binomial(1, np.full(labels.shape, 0.5)).astype("bool")
+ indices_random &= masked_indices & ~indices_replaced
+
+ random_words = np.random.randint(self.tokenizer.vocab_size, size=labels.shape, dtype="i4")
+ inputs[indices_random] = random_words[indices_random]
+
+ # The rest of the time (10% of the time) we keep the masked input tokens unchanged
+ return inputs, labels
+
+
+def generate_batch_splits(samples_idx: np.ndarray, batch_size: int, drop_last=True) -> np.ndarray:
+ """Generate batches of data for a specified batch size from sample indices. If the dataset size is not divisible by
+ the batch size and `drop_last` is `True`, the last incomplete batch is dropped. Else, it is returned."""
+ num_samples = len(samples_idx)
+ if drop_last:
+ samples_to_remove = num_samples % batch_size
+ if samples_to_remove != 0:
+ samples_idx = samples_idx[:-samples_to_remove]
+ sections_split = num_samples // batch_size
+ samples_idx = samples_idx.reshape((sections_split, batch_size))
+ else:
+ sections_split = math.ceil(num_samples / batch_size)
+ samples_idx = np.array_split(samples_idx, sections_split)
+ return samples_idx
+
+
+def write_train_metric(summary_writer, train_metrics, train_time, step):
+ summary_writer.scalar("train_time", train_time, step)
+
+ train_metrics = get_metrics(train_metrics)
+ for key, vals in train_metrics.items():
+ tag = f"train_{key}"
+ for i, val in enumerate(vals):
+ summary_writer.scalar(tag, val, step - len(vals) + i + 1)
+
+
+def write_eval_metric(summary_writer, eval_metrics, step):
+ for metric_name, value in eval_metrics.items():
+ summary_writer.scalar(f"eval_{metric_name}", value, step)
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_mlm", model_args, data_args, framework="flax")
+
+ if (
+ os.path.exists(training_args.output_dir)
+ and os.listdir(training_args.output_dir)
+ and training_args.do_train
+ and not training_args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ level=logging.INFO,
+ datefmt="[%X]",
+ )
+
+ # Log on each process the small summary:
+ logger = logging.getLogger(__name__)
+
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Handle the repository creation
+ if training_args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = training_args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(training_args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=training_args.hub_token).repo_id
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantees that only one local process can concurrently
+ # download the dataset.
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ if "validation" not in datasets.keys():
+ datasets["validation"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ datasets["train"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ if extension == "txt":
+ extension = "text"
+ datasets = load_dataset(
+ extension,
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ )
+
+ if "validation" not in datasets.keys():
+ datasets["validation"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ )
+ datasets["train"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ )
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ if model_args.config_name:
+ config = AutoConfig.from_pretrained(
+ model_args.config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ elif model_args.model_name_or_path:
+ config = AutoConfig.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ config = CONFIG_MAPPING[model_args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ if model_args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ elif model_args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ if training_args.do_train:
+ column_names = datasets["train"].column_names
+ else:
+ column_names = datasets["validation"].column_names
+ text_column_name = "text" if "text" in column_names else column_names[0]
+
+ max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
+
+ if data_args.line_by_line:
+ # When using line_by_line, we just tokenize each nonempty line.
+ padding = "max_length" if data_args.pad_to_max_length else False
+
+ def tokenize_function(examples):
+ # Remove empty lines
+ examples = [line for line in examples if len(line) > 0 and not line.isspace()]
+ return tokenizer(
+ examples,
+ return_special_tokens_mask=True,
+ padding=padding,
+ truncation=True,
+ max_length=max_seq_length,
+ )
+
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ input_columns=[text_column_name],
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ )
+
+ else:
+ # Otherwise, we tokenize every text, then concatenate them together before splitting them in smaller parts.
+ # We use `return_special_tokens_mask=True` because DataCollatorForLanguageModeling (see below) is more
+ # efficient when it receives the `special_tokens_mask`.
+ def tokenize_function(examples):
+ return tokenizer(examples[text_column_name], return_special_tokens_mask=True)
+
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ )
+
+ # Main data processing function that will concatenate all texts from our dataset and generate chunks of
+ # max_seq_length.
+ def group_texts(examples):
+ # Concatenate all texts.
+ concatenated_examples = {k: list(chain(*examples[k])) for k in examples.keys()}
+ total_length = len(concatenated_examples[list(examples.keys())[0]])
+ # We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
+ # customize this part to your needs.
+ if total_length >= max_seq_length:
+ total_length = (total_length // max_seq_length) * max_seq_length
+ # Split by chunks of max_len.
+ result = {
+ k: [t[i : i + max_seq_length] for i in range(0, total_length, max_seq_length)]
+ for k, t in concatenated_examples.items()
+ }
+ return result
+
+ # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a
+ # remainder for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value
+ # might be slower to preprocess.
+ #
+ # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
+ # https://huggingface.co/docs/datasets/process#map
+ tokenized_datasets = tokenized_datasets.map(
+ group_texts,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ )
+
+ # Enable tensorboard only on the master node
+ has_tensorboard = is_tensorboard_available()
+ if has_tensorboard and jax.process_index() == 0:
+ try:
+ from flax.metrics.tensorboard import SummaryWriter
+
+ summary_writer = SummaryWriter(log_dir=Path(training_args.output_dir))
+ except ImportError as ie:
+ has_tensorboard = False
+ logger.warning(
+ f"Unable to display metrics through TensorBoard because some package are not installed: {ie}"
+ )
+ else:
+ logger.warning(
+ "Unable to display metrics through TensorBoard because the package is not installed: "
+ "Please run pip install tensorboard to enable."
+ )
+
+ # Data collator
+ # This one will take care of randomly masking the tokens.
+ data_collator = FlaxDataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=data_args.mlm_probability)
+
+ # Initialize our training
+ rng = jax.random.PRNGKey(training_args.seed)
+ dropout_rngs = jax.random.split(rng, jax.local_device_count())
+
+ if model_args.model_name_or_path:
+ model = FlaxAutoModelForMaskedLM.from_pretrained(
+ model_args.model_name_or_path,
+ config=config,
+ seed=training_args.seed,
+ dtype=getattr(jnp, model_args.dtype),
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ model = FlaxAutoModelForMaskedLM.from_config(
+ config,
+ seed=training_args.seed,
+ dtype=getattr(jnp, model_args.dtype),
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ if training_args.gradient_checkpointing:
+ model.enable_gradient_checkpointing()
+
+ # Store some constant
+ num_epochs = int(training_args.num_train_epochs)
+ train_batch_size = int(training_args.per_device_train_batch_size) * jax.device_count()
+ per_device_eval_batch_size = int(training_args.per_device_eval_batch_size)
+ eval_batch_size = per_device_eval_batch_size * jax.device_count()
+
+ num_train_steps = len(tokenized_datasets["train"]) // train_batch_size * num_epochs
+
+ # Create learning rate schedule
+ warmup_fn = optax.linear_schedule(
+ init_value=0.0, end_value=training_args.learning_rate, transition_steps=training_args.warmup_steps
+ )
+ decay_fn = optax.linear_schedule(
+ init_value=training_args.learning_rate,
+ end_value=0,
+ transition_steps=num_train_steps - training_args.warmup_steps,
+ )
+ linear_decay_lr_schedule_fn = optax.join_schedules(
+ schedules=[warmup_fn, decay_fn], boundaries=[training_args.warmup_steps]
+ )
+
+ # We use Optax's "masking" functionality to not apply weight decay
+ # to bias and LayerNorm scale parameters. decay_mask_fn returns a
+ # mask boolean with the same structure as the parameters.
+ # The mask is True for parameters that should be decayed.
+ def decay_mask_fn(params):
+ flat_params = traverse_util.flatten_dict(params)
+ # find out all LayerNorm parameters
+ layer_norm_candidates = ["layernorm", "layer_norm", "ln"]
+ layer_norm_named_params = {
+ layer[-2:]
+ for layer_norm_name in layer_norm_candidates
+ for layer in flat_params.keys()
+ if layer_norm_name in "".join(layer).lower()
+ }
+ flat_mask = {path: (path[-1] != "bias" and path[-2:] not in layer_norm_named_params) for path in flat_params}
+ return traverse_util.unflatten_dict(flat_mask)
+
+ # create adam optimizer
+ if training_args.adafactor:
+ # We use the default parameters here to initialize adafactor,
+ # For more details about the parameters please check https://github.com/deepmind/optax/blob/ed02befef9bf81cbbf236be3d2b0e032e9ed4a40/optax/_src/alias.py#L74
+ optimizer = optax.adafactor(
+ learning_rate=linear_decay_lr_schedule_fn,
+ )
+ else:
+ optimizer = optax.adamw(
+ learning_rate=linear_decay_lr_schedule_fn,
+ b1=training_args.adam_beta1,
+ b2=training_args.adam_beta2,
+ eps=training_args.adam_epsilon,
+ weight_decay=training_args.weight_decay,
+ mask=decay_mask_fn,
+ )
+
+ # Setup train state
+ state = train_state.TrainState.create(apply_fn=model.__call__, params=model.params, tx=optimizer)
+
+ # Define gradient update step fn
+ def train_step(state, batch, dropout_rng):
+ dropout_rng, new_dropout_rng = jax.random.split(dropout_rng)
+
+ def loss_fn(params):
+ labels = batch.pop("labels")
+
+ logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
+
+ # compute loss, ignore padded input tokens
+ label_mask = jnp.where(labels > 0, 1.0, 0.0)
+ loss = optax.softmax_cross_entropy(logits, onehot(labels, logits.shape[-1])) * label_mask
+
+ # take average
+ loss = loss.sum()
+ num_labels = label_mask.sum()
+
+ return loss, num_labels
+
+ grad_fn = jax.value_and_grad(loss_fn, has_aux=True)
+ (loss, num_labels), grad = grad_fn(state.params)
+ num_labels = jax.lax.psum(num_labels, "batch")
+
+ # true loss = total loss / total samples
+ loss = jax.lax.psum(loss, "batch")
+ loss = jax.tree_util.tree_map(lambda x: x / num_labels, loss)
+
+ # true grad = total grad / total samples
+ grad = jax.lax.psum(grad, "batch")
+ grad = jax.tree_util.tree_map(lambda x: x / num_labels, grad)
+ new_state = state.apply_gradients(grads=grad)
+
+ metrics = {"loss": loss, "learning_rate": linear_decay_lr_schedule_fn(state.step)}
+
+ return new_state, metrics, new_dropout_rng
+
+ # Create parallel version of the train step
+ p_train_step = jax.pmap(train_step, "batch", donate_argnums=(0,))
+
+ # Define eval fn
+ def eval_step(params, batch):
+ labels = batch.pop("labels")
+
+ logits = model(**batch, params=params, train=False)[0]
+
+ # compute loss, ignore padded input tokens
+ label_mask = jnp.where(labels > 0, 1.0, 0.0)
+ loss = optax.softmax_cross_entropy(logits, onehot(labels, logits.shape[-1])) * label_mask
+
+ # compute accuracy
+ accuracy = jnp.equal(jnp.argmax(logits, axis=-1), labels) * label_mask
+
+ # summarize metrics
+ metrics = {"loss": loss.sum(), "accuracy": accuracy.sum(), "normalizer": label_mask.sum()}
+ metrics = jax.lax.psum(metrics, axis_name="batch")
+
+ return metrics
+
+ p_eval_step = jax.pmap(eval_step, "batch", donate_argnums=(0,))
+
+ # Replicate the train state on each device
+ state = jax_utils.replicate(state)
+
+ train_time = 0
+ epochs = tqdm(range(num_epochs), desc=f"Epoch ... (1/{num_epochs})", position=0)
+ for epoch in epochs:
+ # ======================== Training ================================
+ train_start = time.time()
+ train_metrics = []
+
+ # Create sampling rng
+ rng, input_rng = jax.random.split(rng)
+
+ # Generate an epoch by shuffling sampling indices from the train dataset
+ num_train_samples = len(tokenized_datasets["train"])
+ # Avoid using jax.numpy here in case of TPU training
+ train_samples_idx = np.random.permutation(np.arange(num_train_samples))
+ train_batch_idx = generate_batch_splits(train_samples_idx, train_batch_size)
+
+ # Gather the indexes for creating the batch and do a training step
+ for step, batch_idx in enumerate(tqdm(train_batch_idx, desc="Training...", position=1)):
+ samples = [tokenized_datasets["train"][int(idx)] for idx in batch_idx]
+ model_inputs = data_collator(samples, pad_to_multiple_of=16)
+
+ # Model forward
+ model_inputs = shard(model_inputs.data)
+ state, train_metric, dropout_rngs = p_train_step(state, model_inputs, dropout_rngs)
+ train_metrics.append(train_metric)
+
+ cur_step = epoch * (num_train_samples // train_batch_size) + step
+
+ if cur_step % training_args.logging_steps == 0 and cur_step > 0:
+ # Save metrics
+ train_metric = jax_utils.unreplicate(train_metric)
+ train_time += time.time() - train_start
+ if has_tensorboard and jax.process_index() == 0:
+ write_train_metric(summary_writer, train_metrics, train_time, cur_step)
+
+ epochs.write(
+ f"Step... ({cur_step} | Loss: {train_metric['loss']}, Learning Rate:"
+ f" {train_metric['learning_rate']})"
+ )
+
+ train_metrics = []
+
+ if cur_step % training_args.eval_steps == 0 and cur_step > 0:
+ # ======================== Evaluating ==============================
+ num_eval_samples = len(tokenized_datasets["validation"])
+ # Avoid using jax.numpy here in case of TPU training
+ eval_samples_idx = np.arange(num_eval_samples)
+ eval_batch_idx = generate_batch_splits(eval_samples_idx, eval_batch_size, drop_last=False)
+
+ eval_metrics = []
+ for i, batch_idx in enumerate(tqdm(eval_batch_idx, desc="Evaluating ...", position=2)):
+ samples = [tokenized_datasets["validation"][int(idx)] for idx in batch_idx]
+ model_inputs = data_collator(samples, pad_to_multiple_of=16)
+
+ # Model forward
+ metrics = pad_shard_unpad(p_eval_step, static_return=True)(
+ state.params, model_inputs.data, min_device_batch=per_device_eval_batch_size
+ )
+ eval_metrics.append(metrics)
+
+ # normalize eval metrics
+ eval_metrics = get_metrics(eval_metrics)
+ eval_metrics = jax.tree_util.tree_map(jnp.sum, eval_metrics)
+ eval_normalizer = eval_metrics.pop("normalizer")
+ eval_metrics = jax.tree_util.tree_map(lambda x: x / eval_normalizer, eval_metrics)
+
+ # Update progress bar
+ epochs.desc = f"Step... ({cur_step} | Loss: {eval_metrics['loss']}, Acc: {eval_metrics['accuracy']})"
+
+ # Save metrics
+ if has_tensorboard and jax.process_index() == 0:
+ write_eval_metric(summary_writer, eval_metrics, cur_step)
+
+ if cur_step % training_args.save_steps == 0 and cur_step > 0:
+ # save checkpoint after each epoch and push checkpoint to the hub
+ if jax.process_index() == 0:
+ params = jax.device_get(jax.tree_util.tree_map(lambda x: x[0], state.params))
+ model.save_pretrained(training_args.output_dir, params=params)
+ tokenizer.save_pretrained(training_args.output_dir)
+ if training_args.push_to_hub:
+ api.upload_folder(
+ commit_message=f"Saving weights and logs of step {cur_step}",
+ folder_path=training_args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=training_args.hub_token,
+ )
+ # Eval after training
+ if training_args.do_eval:
+ num_eval_samples = len(tokenized_datasets["validation"])
+ # Avoid using jax.numpy here in case of TPU training
+ eval_samples_idx = np.arange(num_eval_samples)
+ eval_batch_idx = generate_batch_splits(eval_samples_idx, eval_batch_size, drop_last=False)
+
+ eval_metrics = []
+ for _, batch_idx in enumerate(tqdm(eval_batch_idx, desc="Evaluating ...", position=2)):
+ samples = [tokenized_datasets["validation"][int(idx)] for idx in batch_idx]
+ model_inputs = data_collator(samples, pad_to_multiple_of=16)
+
+ # Model forward
+ metrics = pad_shard_unpad(p_eval_step, static_return=True)(
+ state.params, model_inputs.data, min_device_batch=per_device_eval_batch_size
+ )
+ eval_metrics.append(metrics)
+
+ # normalize eval metrics
+ eval_metrics = get_metrics(eval_metrics)
+ eval_metrics = jax.tree_util.tree_map(lambda metric: jnp.sum(metric).item(), eval_metrics)
+ eval_normalizer = eval_metrics.pop("normalizer")
+ eval_metrics = jax.tree_util.tree_map(lambda x: x / eval_normalizer, eval_metrics)
+
+ try:
+ perplexity = math.exp(eval_metrics["loss"])
+ except OverflowError:
+ perplexity = float("inf")
+ eval_metrics["perplexity"] = perplexity
+
+ if jax.process_index() == 0:
+ eval_metrics = {f"eval_{metric_name}": value for metric_name, value in eval_metrics.items()}
+ path = os.path.join(training_args.output_dir, "eval_results.json")
+ with open(path, "w") as f:
+ json.dump(eval_metrics, f, indent=4, sort_keys=True)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/run_t5_mlm_flax.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/run_t5_mlm_flax.py
new file mode 100644
index 0000000000000000000000000000000000000000..c133824fcc2c18e4cc48f86343ac251266e5eda1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/run_t5_mlm_flax.py
@@ -0,0 +1,1014 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Pretraining the library models for T5-like span-masked language modeling on a text file or a dataset.
+
+Here is the full list of checkpoints on the hub that can be pretrained by this script:
+https://huggingface.co/models?filter=t5
+"""
+
+import json
+import logging
+import math
+import os
+import sys
+import time
+from dataclasses import asdict, dataclass, field
+
+# You can also adapt this script on your own masked language modeling task. Pointers for this are left as comments.
+from enum import Enum
+from itertools import chain
+from pathlib import Path
+from typing import Dict, List, Optional
+
+import flax
+import jax
+import jax.numpy as jnp
+import numpy as np
+import optax
+from datasets import load_dataset
+from flax import jax_utils, traverse_util
+from flax.jax_utils import pad_shard_unpad
+from flax.training import train_state
+from flax.training.common_utils import get_metrics, onehot, shard
+from huggingface_hub import HfApi
+from tqdm import tqdm
+
+from transformers import (
+ CONFIG_MAPPING,
+ FLAX_MODEL_FOR_MASKED_LM_MAPPING,
+ AutoTokenizer,
+ BatchEncoding,
+ FlaxT5ForConditionalGeneration,
+ HfArgumentParser,
+ PreTrainedTokenizerBase,
+ T5Config,
+ is_tensorboard_available,
+ set_seed,
+)
+from transformers.models.t5.modeling_flax_t5 import shift_tokens_right
+from transformers.utils import send_example_telemetry
+
+
+MODEL_CONFIG_CLASSES = list(FLAX_MODEL_FOR_MASKED_LM_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+@dataclass
+class TrainingArguments:
+ output_dir: str = field(
+ metadata={"help": "The output directory where the model predictions and checkpoints will be written."},
+ )
+ overwrite_output_dir: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Overwrite the content of the output directory. "
+ "Use this to continue training if output_dir points to a checkpoint directory."
+ )
+ },
+ )
+ do_train: bool = field(default=False, metadata={"help": "Whether to run training."})
+ do_eval: bool = field(default=False, metadata={"help": "Whether to run eval on the dev set."})
+ per_device_train_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for training."}
+ )
+ per_device_eval_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for evaluation."}
+ )
+ learning_rate: float = field(default=5e-5, metadata={"help": "The initial learning rate for AdamW."})
+ weight_decay: float = field(default=0.0, metadata={"help": "Weight decay for AdamW if we apply some."})
+ adam_beta1: float = field(default=0.9, metadata={"help": "Beta1 for AdamW optimizer"})
+ adam_beta2: float = field(default=0.999, metadata={"help": "Beta2 for AdamW optimizer"})
+ adam_epsilon: float = field(default=1e-8, metadata={"help": "Epsilon for AdamW optimizer."})
+ adafactor: bool = field(default=False, metadata={"help": "Whether or not to replace AdamW by Adafactor."})
+ num_train_epochs: float = field(default=3.0, metadata={"help": "Total number of training epochs to perform."})
+ warmup_steps: int = field(default=0, metadata={"help": "Linear warmup over warmup_steps."})
+ logging_steps: int = field(default=500, metadata={"help": "Log every X updates steps."})
+ save_steps: int = field(default=500, metadata={"help": "Save checkpoint every X updates steps."})
+ eval_steps: int = field(default=None, metadata={"help": "Run an evaluation every X steps."})
+ seed: int = field(default=42, metadata={"help": "Random seed that will be set at the beginning of training."})
+ push_to_hub: bool = field(
+ default=False, metadata={"help": "Whether or not to upload the trained model to the model hub after training."}
+ )
+ hub_model_id: str = field(
+ default=None, metadata={"help": "The name of the repository to keep in sync with the local `output_dir`."}
+ )
+ hub_token: str = field(default=None, metadata={"help": "The token to use to push to the Model Hub."})
+
+ def __post_init__(self):
+ if self.output_dir is not None:
+ self.output_dir = os.path.expanduser(self.output_dir)
+
+ def to_dict(self):
+ """
+ Serializes this instance while replace `Enum` by their values (for JSON serialization support). It obfuscates
+ the token values by removing their value.
+ """
+ d = asdict(self)
+ for k, v in d.items():
+ if isinstance(v, Enum):
+ d[k] = v.value
+ if isinstance(v, list) and len(v) > 0 and isinstance(v[0], Enum):
+ d[k] = [x.value for x in v]
+ if k.endswith("_token"):
+ d[k] = f"<{k.upper()}>"
+ return d
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ model_name_or_path: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
+ )
+ },
+ )
+ model_type: Optional[str] = field(
+ default=None,
+ metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ dtype: Optional[str] = field(
+ default="float32",
+ metadata={
+ "help": (
+ "Floating-point format in which the model weights should be initialized and trained. Choose one of"
+ " `[float32, float16, bfloat16]`."
+ )
+ },
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ train_ref_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input train ref data file for whole word masking in Chinese."},
+ )
+ validation_ref_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input validation ref data file for whole word masking in Chinese."},
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ validation_split_percentage: Optional[int] = field(
+ default=5,
+ metadata={
+ "help": "The percentage of the train set used as validation set in case there's no validation split"
+ },
+ )
+ max_seq_length: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization and masking. Sequences longer than this"
+ " will be truncated. Default to the max input length of the model."
+ )
+ },
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ mlm_probability: float = field(
+ default=0.15, metadata={"help": "Ratio of tokens to mask for span masked language modeling loss"}
+ )
+ mean_noise_span_length: float = field(
+ default=3.0,
+ metadata={"help": "Mean span length of masked tokens"},
+ )
+
+ def __post_init__(self):
+ if self.dataset_name is None and self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, a json or a txt file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, a json or a txt file."
+
+
+def compute_input_and_target_lengths(inputs_length, noise_density, mean_noise_span_length):
+ """This function is copy of `random_spans_helper `__ .
+
+ Training parameters to avoid padding with random_spans_noise_mask.
+ When training a model with random_spans_noise_mask, we would like to set the other
+ training hyperparmeters in a way that avoids padding.
+ This function helps us compute these hyperparameters.
+ We assume that each noise span in the input is replaced by extra_tokens_per_span_inputs sentinel tokens,
+ and each non-noise span in the targets is replaced by extra_tokens_per_span_targets sentinel tokens.
+ This function tells us the required number of tokens in the raw example (for split_tokens())
+ as well as the length of the encoded targets. Note that this function assumes
+ the inputs and targets will have EOS appended and includes that in the reported length.
+
+ Args:
+ inputs_length: an integer - desired length of the tokenized inputs sequence
+ noise_density: a float
+ mean_noise_span_length: a float
+ Returns:
+ tokens_length: length of original text in tokens
+ targets_length: an integer - length in tokens of encoded targets sequence
+ """
+
+ def _tokens_length_to_inputs_length_targets_length(tokens_length):
+ num_noise_tokens = int(round(tokens_length * noise_density))
+ num_nonnoise_tokens = tokens_length - num_noise_tokens
+ num_noise_spans = int(round(num_noise_tokens / mean_noise_span_length))
+ # inputs contain all nonnoise tokens, sentinels for all noise spans
+ # and one EOS token.
+ _input_length = num_nonnoise_tokens + num_noise_spans + 1
+ _output_length = num_noise_tokens + num_noise_spans + 1
+ return _input_length, _output_length
+
+ tokens_length = inputs_length
+
+ while _tokens_length_to_inputs_length_targets_length(tokens_length + 1)[0] <= inputs_length:
+ tokens_length += 1
+
+ inputs_length, targets_length = _tokens_length_to_inputs_length_targets_length(tokens_length)
+
+ # minor hack to get the targets length to be equal to inputs length
+ # which is more likely to have been set to a nice round number.
+ if noise_density == 0.5 and targets_length > inputs_length:
+ tokens_length -= 1
+ targets_length -= 1
+ return tokens_length, targets_length
+
+
+@flax.struct.dataclass
+class FlaxDataCollatorForT5MLM:
+ """
+ Data collator used for T5 span-masked language modeling.
+ It is made sure that after masking the inputs are of length `data_args.max_seq_length` and targets are also of fixed length.
+ For more information on how T5 span-masked language modeling works, one can take a look
+ at the `official paper `__
+ or the `official code for preprocessing `__ .
+
+ Args:
+ tokenizer (:class:`~transformers.PreTrainedTokenizer` or :class:`~transformers.PreTrainedTokenizerFast`):
+ The tokenizer used for encoding the data.
+ noise_density (:obj:`float`):
+ The probability with which to (randomly) mask tokens in the input.
+ mean_noise_span_length (:obj:`float`):
+ The average span length of the masked tokens.
+ input_length (:obj:`int`):
+ The expected input length after masking.
+ target_length (:obj:`int`):
+ The expected target length after masking.
+ pad_token_id: (:obj:`int`):
+ The pad token id of the model
+ decoder_start_token_id: (:obj:`int):
+ The decoder start token id of the model
+ """
+
+ tokenizer: PreTrainedTokenizerBase
+ noise_density: float
+ mean_noise_span_length: float
+ input_length: int
+ target_length: int
+ pad_token_id: int
+ decoder_start_token_id: int
+
+ def __call__(self, examples: List[Dict[str, np.ndarray]]) -> BatchEncoding:
+ # convert list to dict and tensorize input
+ batch = BatchEncoding(
+ {k: np.array([examples[i][k] for i in range(len(examples))]) for k, v in examples[0].items()}
+ )
+
+ input_ids = batch["input_ids"]
+ batch_size, expandend_input_length = input_ids.shape
+
+ mask_indices = np.asarray([self.random_spans_noise_mask(expandend_input_length) for i in range(batch_size)])
+ labels_mask = ~mask_indices
+
+ input_ids_sentinel = self.create_sentinel_ids(mask_indices.astype(np.int8))
+ labels_sentinel = self.create_sentinel_ids(labels_mask.astype(np.int8))
+
+ batch["input_ids"] = self.filter_input_ids(input_ids, input_ids_sentinel)
+ batch["labels"] = self.filter_input_ids(input_ids, labels_sentinel)
+
+ if batch["input_ids"].shape[-1] != self.input_length:
+ raise ValueError(
+ f"`input_ids` are incorrectly preprocessed. `input_ids` length is {batch['input_ids'].shape[-1]}, but"
+ f" should be {self.input_length}."
+ )
+
+ if batch["labels"].shape[-1] != self.target_length:
+ raise ValueError(
+ f"`labels` are incorrectly preprocessed. `labels` length is {batch['labels'].shape[-1]}, but should be"
+ f" {self.target_length}."
+ )
+
+ # to check that tokens are correctly preprocessed, one can run `self.tokenizer.batch_decode(input_ids)` and `self.tokenizer.batch_decode(labels)` here...
+ batch["decoder_input_ids"] = shift_tokens_right(
+ batch["labels"], self.pad_token_id, self.decoder_start_token_id
+ )
+
+ return batch
+
+ def create_sentinel_ids(self, mask_indices):
+ """
+ Sentinel ids creation given the indices that should be masked.
+ The start indices of each mask are replaced by the sentinel ids in increasing
+ order. Consecutive mask indices to be deleted are replaced with `-1`.
+ """
+ start_indices = mask_indices - np.roll(mask_indices, 1, axis=-1) * mask_indices
+ start_indices[:, 0] = mask_indices[:, 0]
+
+ sentinel_ids = np.where(start_indices != 0, np.cumsum(start_indices, axis=-1), start_indices)
+ sentinel_ids = np.where(sentinel_ids != 0, (len(self.tokenizer) - sentinel_ids), 0)
+ sentinel_ids -= mask_indices - start_indices
+
+ return sentinel_ids
+
+ def filter_input_ids(self, input_ids, sentinel_ids):
+ """
+ Puts sentinel mask on `input_ids` and fuse consecutive mask tokens into a single mask token by deleting.
+ This will reduce the sequence length from `expanded_inputs_length` to `input_length`.
+ """
+ batch_size = input_ids.shape[0]
+
+ input_ids_full = np.where(sentinel_ids != 0, sentinel_ids, input_ids)
+ # input_ids tokens and sentinel tokens are >= 0, tokens < 0 are
+ # masked tokens coming after sentinel tokens and should be removed
+ input_ids = input_ids_full[input_ids_full >= 0].reshape((batch_size, -1))
+ input_ids = np.concatenate(
+ [input_ids, np.full((batch_size, 1), self.tokenizer.eos_token_id, dtype=np.int32)], axis=-1
+ )
+ return input_ids
+
+ def random_spans_noise_mask(self, length):
+ """This function is copy of `random_spans_helper `__ .
+
+ Noise mask consisting of random spans of noise tokens.
+ The number of noise tokens and the number of noise spans and non-noise spans
+ are determined deterministically as follows:
+ num_noise_tokens = round(length * noise_density)
+ num_nonnoise_spans = num_noise_spans = round(num_noise_tokens / mean_noise_span_length)
+ Spans alternate between non-noise and noise, beginning with non-noise.
+ Subject to the above restrictions, all masks are equally likely.
+
+ Args:
+ length: an int32 scalar (length of the incoming token sequence)
+ noise_density: a float - approximate density of output mask
+ mean_noise_span_length: a number
+
+ Returns:
+ a boolean tensor with shape [length]
+ """
+
+ orig_length = length
+
+ num_noise_tokens = int(np.round(length * self.noise_density))
+ num_nonnoise_tokens = length - num_noise_tokens
+ # avoid degeneracy by ensuring positive numbers of noise and nonnoise tokens.
+ num_noise_tokens = min(max(num_noise_tokens, 1), length - 1)
+ # num_noise_tokens should be less than num_noise_tokens and num_nonnoise_tokens
+ num_noise_spans = int(np.round(min(num_noise_tokens, num_nonnoise_tokens) / self.mean_noise_span_length))
+
+ # avoid degeneracy by ensuring positive number of noise spans
+ num_noise_spans = max(num_noise_spans, 1)
+
+ # pick the lengths of the noise spans and the non-noise spans
+ def _random_segmentation(num_items, num_segments):
+ """Partition a sequence of items randomly into non-empty segments.
+ Args:
+ num_items: an integer scalar > 0
+ num_segments: an integer scalar in [1, num_items]
+ Returns:
+ a Tensor with shape [num_segments] containing positive integers that add
+ up to num_items
+ """
+ mask_indices = np.arange(num_items - 1) < (num_segments - 1)
+ np.random.shuffle(mask_indices)
+ first_in_segment = np.pad(mask_indices, [[1, 0]])
+ segment_id = np.cumsum(first_in_segment)
+ # count length of sub segments assuming that list is sorted
+ _, segment_length = np.unique(segment_id, return_counts=True)
+ return segment_length
+
+ noise_span_lengths = _random_segmentation(num_noise_tokens, num_noise_spans)
+ nonnoise_span_lengths = _random_segmentation(num_nonnoise_tokens, num_noise_spans)
+
+ interleaved_span_lengths = np.reshape(
+ np.stack([nonnoise_span_lengths, noise_span_lengths], axis=1), [num_noise_spans * 2]
+ )
+ span_starts = np.cumsum(interleaved_span_lengths)[:-1]
+ span_start_indicator = np.zeros((length,), dtype=np.int8)
+ span_start_indicator[span_starts] = True
+ span_num = np.cumsum(span_start_indicator)
+ is_noise = np.equal(span_num % 2, 1)
+
+ return is_noise[:orig_length]
+
+
+def generate_batch_splits(samples_idx: np.ndarray, batch_size: int, drop_last=True) -> np.ndarray:
+ """Generate batches of data for a specified batch size from sample indices. If the dataset size is not divisible by
+ the batch size and `drop_last` is `True`, the last incomplete batch is dropped. Else, it is returned."""
+ num_samples = len(samples_idx)
+ if drop_last:
+ samples_to_remove = num_samples % batch_size
+ if samples_to_remove != 0:
+ samples_idx = samples_idx[:-samples_to_remove]
+ sections_split = num_samples // batch_size
+ samples_idx = samples_idx.reshape((sections_split, batch_size))
+ else:
+ sections_split = math.ceil(num_samples / batch_size)
+ samples_idx = np.array_split(samples_idx, sections_split)
+ return samples_idx
+
+
+def write_train_metric(summary_writer, train_metrics, train_time, step):
+ summary_writer.scalar("train_time", train_time, step)
+
+ train_metrics = get_metrics(train_metrics)
+ for key, vals in train_metrics.items():
+ tag = f"train_{key}"
+ for i, val in enumerate(vals):
+ summary_writer.scalar(tag, val, step - len(vals) + i + 1)
+
+
+def write_eval_metric(summary_writer, eval_metrics, step):
+ for metric_name, value in eval_metrics.items():
+ summary_writer.scalar(f"eval_{metric_name}", value, step)
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_t5_mlm", model_args, data_args, framework="flax")
+
+ if (
+ os.path.exists(training_args.output_dir)
+ and os.listdir(training_args.output_dir)
+ and training_args.do_train
+ and not training_args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ level=logging.INFO,
+ datefmt="[%X]",
+ )
+
+ # Log on each process the small summary:
+ logger = logging.getLogger(__name__)
+
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Handle the repository creation
+ if training_args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = training_args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(training_args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=training_args.hub_token).repo_id
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+
+ if "validation" not in datasets.keys():
+ datasets["validation"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+ datasets["train"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ if extension == "txt":
+ extension = "text"
+ datasets = load_dataset(
+ extension,
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ )
+
+ if "validation" not in datasets.keys():
+ datasets["validation"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ )
+ datasets["train"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ num_proc=data_args.preprocessing_num_workers,
+ )
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+
+ if model_args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ token=model_args.token,
+ )
+ elif model_args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ token=model_args.token,
+ )
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if model_args.config_name:
+ config = T5Config.from_pretrained(
+ model_args.config_name,
+ cache_dir=model_args.cache_dir,
+ vocab_size=len(tokenizer),
+ token=model_args.token,
+ )
+ elif model_args.model_name_or_path:
+ config = T5Config.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ else:
+ config = CONFIG_MAPPING[model_args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ if training_args.do_train:
+ column_names = datasets["train"].column_names
+ else:
+ column_names = datasets["validation"].column_names
+ text_column_name = "text" if "text" in column_names else column_names[0]
+
+ max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
+
+ # Otherwise, we tokenize every text, then concatenate them together before splitting them in smaller parts.
+ # Since we make sure that all sequences are of the same length, no attention_mask is needed.
+ def tokenize_function(examples):
+ return tokenizer(examples[text_column_name], return_attention_mask=False)
+
+ tokenized_datasets = datasets.map(
+ tokenize_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ )
+
+ # T5-like span masked language modeling will fuse consecutively masked tokens to a single sentinel token.
+ # To ensure that the input length is `max_seq_length`, we need to increase the maximum length
+ # according to `mlm_probability` and `mean_noise_span_length`. We can also define the label length accordingly.
+ expanded_inputs_length, targets_length = compute_input_and_target_lengths(
+ inputs_length=max_seq_length,
+ noise_density=data_args.mlm_probability,
+ mean_noise_span_length=data_args.mean_noise_span_length,
+ )
+
+ # Main data processing function that will concatenate all texts from our dataset and generate chunks of expanded_inputs_length.
+ def group_texts(examples):
+ # Concatenate all texts.
+ concatenated_examples = {k: list(chain(*examples[k])) for k in examples.keys()}
+ total_length = len(concatenated_examples[list(examples.keys())[0]])
+ # We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
+ # customize this part to your needs.
+ if total_length >= expanded_inputs_length:
+ total_length = (total_length // expanded_inputs_length) * expanded_inputs_length
+ # Split by chunks of max_len.
+ result = {
+ k: [t[i : i + expanded_inputs_length] for i in range(0, total_length, expanded_inputs_length)]
+ for k, t in concatenated_examples.items()
+ }
+ return result
+
+ # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a
+ # remainder for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value
+ # might be slower to preprocess.
+ #
+ # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
+ # https://huggingface.co/docs/datasets/process#map
+ tokenized_datasets = tokenized_datasets.map(
+ group_texts,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ )
+
+ # Enable tensorboard only on the master node
+ has_tensorboard = is_tensorboard_available()
+ if has_tensorboard and jax.process_index() == 0:
+ try:
+ from flax.metrics.tensorboard import SummaryWriter
+
+ summary_writer = SummaryWriter(log_dir=Path(training_args.output_dir))
+ except ImportError as ie:
+ has_tensorboard = False
+ logger.warning(
+ f"Unable to display metrics through TensorBoard because some package are not installed: {ie}"
+ )
+ else:
+ logger.warning(
+ "Unable to display metrics through TensorBoard because the package is not installed: "
+ "Please run pip install tensorboard to enable."
+ )
+
+ # Initialize our training
+ rng = jax.random.PRNGKey(training_args.seed)
+ dropout_rngs = jax.random.split(rng, jax.local_device_count())
+
+ if model_args.model_name_or_path:
+ model = FlaxT5ForConditionalGeneration.from_pretrained(
+ model_args.model_name_or_path,
+ config=config,
+ seed=training_args.seed,
+ dtype=getattr(jnp, model_args.dtype),
+ token=model_args.token,
+ )
+ else:
+ config.vocab_size = len(tokenizer)
+ model = FlaxT5ForConditionalGeneration(
+ config,
+ seed=training_args.seed,
+ dtype=getattr(jnp, model_args.dtype),
+ )
+
+ # Data collator
+ # This one will take care of randomly masking the tokens.
+ data_collator = FlaxDataCollatorForT5MLM(
+ tokenizer=tokenizer,
+ noise_density=data_args.mlm_probability,
+ mean_noise_span_length=data_args.mean_noise_span_length,
+ input_length=max_seq_length,
+ target_length=targets_length,
+ pad_token_id=model.config.pad_token_id,
+ decoder_start_token_id=model.config.decoder_start_token_id,
+ )
+
+ # Store some constant
+ num_epochs = int(training_args.num_train_epochs)
+ train_batch_size = int(training_args.per_device_train_batch_size) * jax.device_count()
+ per_device_eval_batch_size = int(training_args.per_device_eval_batch_size)
+ eval_batch_size = per_device_eval_batch_size * jax.device_count()
+
+ num_train_steps = len(tokenized_datasets["train"]) // train_batch_size * num_epochs
+
+ num_of_hosts = jax.process_count()
+ current_host_idx = jax.process_index()
+
+ # Create learning rate schedule
+ warmup_fn = optax.linear_schedule(
+ init_value=0.0, end_value=training_args.learning_rate, transition_steps=training_args.warmup_steps
+ )
+ decay_fn = optax.linear_schedule(
+ init_value=training_args.learning_rate,
+ end_value=0,
+ transition_steps=num_train_steps - training_args.warmup_steps,
+ )
+ linear_decay_lr_schedule_fn = optax.join_schedules(
+ schedules=[warmup_fn, decay_fn], boundaries=[training_args.warmup_steps]
+ )
+
+ # We use Optax's "masking" functionality to not apply weight decay
+ # to bias and LayerNorm scale parameters. decay_mask_fn returns a
+ # mask boolean with the same structure as the parameters.
+ # The mask is True for parameters that should be decayed.
+ def decay_mask_fn(params):
+ flat_params = traverse_util.flatten_dict(params)
+ # find out all LayerNorm parameters
+ layer_norm_candidates = ["layernorm", "layer_norm", "ln"]
+ layer_norm_named_params = {
+ layer[-2:]
+ for layer_norm_name in layer_norm_candidates
+ for layer in flat_params.keys()
+ if layer_norm_name in "".join(layer).lower()
+ }
+ flat_mask = {path: (path[-1] != "bias" and path[-2:] not in layer_norm_named_params) for path in flat_params}
+ return traverse_util.unflatten_dict(flat_mask)
+
+ # create adam optimizer
+ if training_args.adafactor:
+ # We use the default parameters here to initialize adafactor,
+ # For more details about the parameters please check https://github.com/deepmind/optax/blob/ed02befef9bf81cbbf236be3d2b0e032e9ed4a40/optax/_src/alias.py#L74
+ optimizer = optax.adafactor(
+ learning_rate=linear_decay_lr_schedule_fn,
+ )
+ else:
+ optimizer = optax.adamw(
+ learning_rate=linear_decay_lr_schedule_fn,
+ b1=training_args.adam_beta1,
+ b2=training_args.adam_beta2,
+ weight_decay=training_args.weight_decay,
+ mask=decay_mask_fn,
+ )
+
+ # Setup train state
+ state = train_state.TrainState.create(apply_fn=model.__call__, params=model.params, tx=optimizer)
+
+ # Define gradient update step fn
+ def train_step(state, batch, dropout_rng):
+ dropout_rng, new_dropout_rng = jax.random.split(dropout_rng)
+
+ def loss_fn(params):
+ labels = batch.pop("labels")
+
+ logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
+
+ # compute loss
+ loss = optax.softmax_cross_entropy(logits, onehot(labels, logits.shape[-1])).mean()
+
+ return loss
+
+ grad_fn = jax.value_and_grad(loss_fn)
+ loss, grad = grad_fn(state.params)
+ grad = jax.lax.pmean(grad, "batch")
+ new_state = state.apply_gradients(grads=grad)
+
+ metrics = jax.lax.pmean(
+ {"loss": loss, "learning_rate": linear_decay_lr_schedule_fn(state.step)}, axis_name="batch"
+ )
+
+ return new_state, metrics, new_dropout_rng
+
+ # Create parallel version of the train step
+ p_train_step = jax.pmap(train_step, "batch", donate_argnums=(0,))
+
+ # Define eval fn
+ def eval_step(params, batch):
+ labels = batch.pop("labels")
+
+ logits = model(**batch, params=params, train=False)[0]
+
+ # compute loss
+ loss = optax.softmax_cross_entropy(logits, onehot(labels, logits.shape[-1]))
+
+ # compute accuracy
+ accuracy = jnp.equal(jnp.argmax(logits, axis=-1), labels)
+
+ # summarize metrics
+ metrics = {"loss": loss.mean(), "accuracy": accuracy.mean()}
+ metrics = jax.lax.pmean(metrics, axis_name="batch")
+
+ return metrics
+
+ p_eval_step = jax.pmap(eval_step, "batch", donate_argnums=(0,))
+
+ # Replicate the train state on each device
+ state = jax_utils.replicate(state)
+
+ train_time = 0
+ epochs = tqdm(range(num_epochs), desc="Epoch ... ", position=0)
+ for epoch in epochs:
+ # ======================== Training ================================
+ train_start = time.time()
+ train_metrics = []
+
+ # Create sampling rng
+ rng, input_rng = jax.random.split(rng)
+
+ # Generate an epoch by shuffling sampling indices from the train dataset
+ num_train_samples = len(tokenized_datasets["train"])
+ # Avoid using jax.numpy here in case of TPU training
+ train_samples_idx = np.random.permutation(np.arange(num_train_samples))
+ train_batch_idx = generate_batch_splits(train_samples_idx, train_batch_size)
+
+ # Gather the indexes for creating the batch and do a training step
+ for step, batch_idx in enumerate(tqdm(train_batch_idx, desc="Training...", position=1)):
+ samples = [tokenized_datasets["train"][int(idx)] for idx in batch_idx]
+ model_inputs = data_collator(samples)
+
+ local_host_model_inputs = {
+ key: np.split(model_inputs.data[key], num_of_hosts, axis=0)[current_host_idx]
+ for key, value in model_inputs.data.items()
+ }
+
+ # Model forward
+ model_inputs = shard(local_host_model_inputs)
+ state, train_metric, dropout_rngs = p_train_step(state, model_inputs, dropout_rngs)
+ train_metrics.append(train_metric)
+
+ cur_step = epoch * (num_train_samples // train_batch_size) + step
+
+ if cur_step % training_args.logging_steps == 0 and cur_step > 0:
+ # Save metrics
+ train_metric = jax_utils.unreplicate(train_metric)
+ train_time += time.time() - train_start
+ if has_tensorboard and jax.process_index() == 0:
+ write_train_metric(summary_writer, train_metrics, train_time, cur_step)
+
+ epochs.write(
+ f"Step... ({cur_step} | Loss: {train_metric['loss'].mean()}, Learning Rate:"
+ f" {train_metric['learning_rate'].mean()})"
+ )
+
+ train_metrics = []
+
+ if cur_step % training_args.eval_steps == 0 and cur_step > 0:
+ # ======================== Evaluating ==============================
+ num_eval_samples = len(tokenized_datasets["validation"])
+ # Avoid using jax.numpy here in case of TPU training
+ eval_samples_idx = np.arange(num_eval_samples)
+ eval_batch_idx = generate_batch_splits(eval_samples_idx, eval_batch_size, drop_last=False)
+
+ eval_metrics = []
+ for i, batch_idx in enumerate(tqdm(eval_batch_idx, desc="Evaluating ...", position=2)):
+ samples = [tokenized_datasets["validation"][int(idx)] for idx in batch_idx]
+ model_inputs = data_collator(samples)
+
+ # Model forward
+ metrics = pad_shard_unpad(p_eval_step, static_return=True)(
+ state.params, model_inputs.data, min_device_batch=per_device_eval_batch_size
+ )
+ eval_metrics.append(metrics)
+
+ # get eval metrics
+ eval_metrics = get_metrics(eval_metrics)
+ eval_metrics = jax.tree_util.tree_map(jnp.mean, eval_metrics)
+
+ # Update progress bar
+ epochs.write(f"Step... ({cur_step} | Loss: {eval_metrics['loss']}, Acc: {eval_metrics['accuracy']})")
+
+ # Save metrics
+ if has_tensorboard and jax.process_index() == 0:
+ write_eval_metric(summary_writer, eval_metrics, cur_step)
+
+ if cur_step % training_args.save_steps == 0 and cur_step > 0:
+ # save checkpoint after each epoch and push checkpoint to the hub
+ if jax.process_index() == 0:
+ params = jax.device_get(jax.tree_util.tree_map(lambda x: x[0], state.params))
+ model.save_pretrained(training_args.output_dir, params=params)
+ tokenizer.save_pretrained(training_args.output_dir)
+ if training_args.push_to_hub:
+ api.upload_folder(
+ commit_message=f"Saving weights and logs of step {cur_step}",
+ folder_path=training_args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=training_args.hub_token,
+ )
+ # Eval after training
+ if training_args.do_eval:
+ num_eval_samples = len(tokenized_datasets["validation"])
+ # Avoid using jax.numpy here in case of TPU training
+ eval_samples_idx = np.arange(num_eval_samples)
+ eval_batch_idx = generate_batch_splits(eval_samples_idx, eval_batch_size, drop_last=False)
+
+ eval_metrics = []
+ for i, batch_idx in enumerate(tqdm(eval_batch_idx, desc="Evaluating ...", position=2)):
+ samples = [tokenized_datasets["validation"][int(idx)] for idx in batch_idx]
+ model_inputs = data_collator(samples)
+
+ # Model forward
+ metrics = pad_shard_unpad(p_eval_step, static_return=True)(
+ state.params, model_inputs.data, min_device_batch=per_device_eval_batch_size
+ )
+ eval_metrics.append(metrics)
+
+ # get eval metrics
+ eval_metrics = get_metrics(eval_metrics)
+ eval_metrics = jax.tree_util.tree_map(lambda metric: jnp.mean(metric).item(), eval_metrics)
+
+ if jax.process_index() == 0:
+ eval_metrics = {f"eval_{metric_name}": value for metric_name, value in eval_metrics.items()}
+ path = os.path.join(training_args.output_dir, "eval_results.json")
+ with open(path, "w") as f:
+ json.dump(eval_metrics, f, indent=4, sort_keys=True)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/t5_tokenizer_model.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/t5_tokenizer_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..a2be4afc94628490a888e97e3157665b743c6307
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/language-modeling/t5_tokenizer_model.py
@@ -0,0 +1,116 @@
+#!/usr/bin/env python3
+import json
+from typing import Iterator, List, Union
+
+from tokenizers import AddedToken, Regex, Tokenizer, decoders, normalizers, pre_tokenizers, trainers
+from tokenizers.implementations.base_tokenizer import BaseTokenizer
+from tokenizers.models import Unigram
+from tokenizers.processors import TemplateProcessing
+
+
+class SentencePieceUnigramTokenizer(BaseTokenizer):
+ """
+ This class is a copy of `DeDLOC's tokenizer implementation `__ .
+
+ Custom SentencePiece Unigram Tokenizer with NMT, NKFC, spaces and lower-casing characters normalization
+ Represents the Unigram algorithm, with the pretokenization used by SentencePiece
+ """
+
+ def __init__(
+ self,
+ replacement: str = "▁",
+ add_prefix_space: bool = True,
+ unk_token: Union[str, AddedToken] = "",
+ eos_token: Union[str, AddedToken] = "",
+ pad_token: Union[str, AddedToken] = "",
+ ):
+ self.special_tokens = {
+ "pad": {"id": 0, "token": pad_token},
+ "eos": {"id": 1, "token": eos_token},
+ "unk": {"id": 2, "token": unk_token},
+ }
+
+ self.special_tokens_list = [None] * len(self.special_tokens)
+ for token_dict in self.special_tokens.values():
+ self.special_tokens_list[token_dict["id"]] = token_dict["token"]
+
+ tokenizer = Tokenizer(Unigram())
+
+ tokenizer.normalizer = normalizers.Sequence(
+ [
+ normalizers.Nmt(),
+ normalizers.NFKC(),
+ normalizers.Replace(Regex(" {2,}"), " "),
+ normalizers.Lowercase(),
+ ]
+ )
+ tokenizer.pre_tokenizer = pre_tokenizers.Sequence(
+ [
+ pre_tokenizers.Metaspace(
+ replacement=replacement, prepend_scheme="always" if add_prefix_space else "never"
+ ),
+ pre_tokenizers.Digits(individual_digits=True),
+ pre_tokenizers.Punctuation(),
+ ]
+ )
+ tokenizer.decoder = decoders.Metaspace(
+ replacement=replacement, prepend_scheme="always" if add_prefix_space else "never"
+ )
+
+ tokenizer.post_processor = TemplateProcessing(
+ single=f"$A {self.special_tokens['eos']['token']}",
+ special_tokens=[(self.special_tokens["eos"]["token"], self.special_tokens["eos"]["id"])],
+ )
+
+ parameters = {
+ "model": "SentencePieceUnigram",
+ "replacement": replacement,
+ "add_prefix_space": add_prefix_space,
+ }
+
+ super().__init__(tokenizer, parameters)
+
+ def train(
+ self,
+ files: Union[str, List[str]],
+ vocab_size: int = 8000,
+ show_progress: bool = True,
+ ):
+ """Train the model using the given files"""
+
+ trainer = trainers.UnigramTrainer(
+ vocab_size=vocab_size,
+ special_tokens=self.special_tokens_list,
+ show_progress=show_progress,
+ )
+
+ if isinstance(files, str):
+ files = [files]
+ self._tokenizer.train(files, trainer=trainer)
+
+ self.add_unk_id()
+
+ def train_from_iterator(
+ self,
+ iterator: Union[Iterator[str], Iterator[Iterator[str]]],
+ vocab_size: int = 8000,
+ show_progress: bool = True,
+ ):
+ """Train the model using the given iterator"""
+
+ trainer = trainers.UnigramTrainer(
+ vocab_size=vocab_size,
+ special_tokens=self.special_tokens_list,
+ show_progress=show_progress,
+ )
+
+ self._tokenizer.train_from_iterator(iterator, trainer=trainer)
+
+ self.add_unk_id()
+
+ def add_unk_id(self):
+ tokenizer_json = json.loads(self._tokenizer.to_str())
+
+ tokenizer_json["model"]["unk_id"] = self.special_tokens["unk"]["id"]
+
+ self._tokenizer = Tokenizer.from_str(json.dumps(tokenizer_json))
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/question-answering/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/question-answering/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..2f6caa984d4bc19cabc32e6a23daa6a3cfacaf6f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/question-answering/README.md
@@ -0,0 +1,104 @@
+
+
+# Question Answering examples
+
+Based on the script [`run_qa.py`](https://github.com/huggingface/transformers/blob/main/examples/flax/question-answering/run_qa.py).
+
+**Note:** This script only works with models that have a fast tokenizer (backed by the 🤗 Tokenizers library) as it
+uses special features of those tokenizers. You can check if your favorite model has a fast tokenizer in
+[this table](https://huggingface.co/transformers/index.html#supported-frameworks), if it doesn't you can still use the old version
+of the script.
+
+
+The following example fine-tunes BERT on SQuAD:
+
+
+```bash
+python run_qa.py \
+ --model_name_or_path google-bert/bert-base-uncased \
+ --dataset_name squad \
+ --do_train \
+ --do_eval \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --learning_rate 3e-5 \
+ --num_train_epochs 2 \
+ --per_device_train_batch_size 12 \
+ --output_dir ./bert-qa-squad \
+ --eval_steps 1000 \
+ --push_to_hub
+```
+
+Using the command above, the script will train for 2 epochs and run eval after each epoch.
+Metrics and hyperparameters are stored in Tensorflow event files in `--output_dir`.
+You can see the results by running `tensorboard` in that directory:
+
+```bash
+$ tensorboard --logdir .
+```
+
+or directly on the hub under *Training metrics*.
+
+Training with the previously defined hyper-parameters yields the following results:
+
+```bash
+f1 = 88.62
+exact_match = 81.34
+```
+
+sample Metrics - [tfhub.dev](https://tensorboard.dev/experiment/6gU75Hx8TGCnc6tr4ZgI9Q)
+
+Here is an example training on 4 TITAN RTX GPUs and Bert Whole Word Masking uncased model to reach a F1 > 93 on SQuAD1.1:
+
+```bash
+export CUDA_VISIBLE_DEVICES=0,1,2,3
+python run_qa.py \
+--model_name_or_path google-bert/bert-large-uncased-whole-word-masking \
+--dataset_name squad \
+--do_train \
+--do_eval \
+--per_device_train_batch_size 6 \
+--learning_rate 3e-5 \
+--num_train_epochs 2 \
+--max_seq_length 384 \
+--doc_stride 128 \
+--output_dir ./wwm_uncased_finetuned_squad/ \
+--eval_steps 1000 \
+--push_to_hub
+```
+
+Training with the previously defined hyper-parameters yields the following results:
+
+```bash
+f1 = 93.31
+exact_match = 87.04
+```
+
+
+### Usage notes
+
+Note that when contexts are long they may be split into multiple training cases, not all of which may contain
+the answer span.
+
+As-is, the example script will train on SQuAD or any other question-answering dataset formatted the same way, and can handle user
+inputs as well.
+
+### Memory usage and data loading
+
+One thing to note is that all data is loaded into memory in this script. Most question answering datasets are small
+enough that this is not an issue, but if you have a very large dataset you will need to modify the script to handle
+data streaming.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/question-answering/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/question-answering/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..e7bf43910c3c8aa6ee05dec90748834304430e0f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/question-answering/requirements.txt
@@ -0,0 +1,5 @@
+datasets >= 1.8.0
+jax>=0.2.17
+jaxlib>=0.1.68
+flax>=0.3.5
+optax>=0.0.8
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/question-answering/run_qa.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/question-answering/run_qa.py
new file mode 100644
index 0000000000000000000000000000000000000000..692a43f9d23cdd4f99efce61aca2ee3f73896870
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/question-answering/run_qa.py
@@ -0,0 +1,1086 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for question answering.
+"""
+# You can also adapt this script on your own question answering task. Pointers for this are left as comments.
+
+import json
+import logging
+import math
+import os
+import random
+import sys
+import time
+from dataclasses import asdict, dataclass, field
+from enum import Enum
+from pathlib import Path
+from typing import Any, Callable, Dict, Optional, Tuple
+
+import datasets
+import evaluate
+import jax
+import jax.numpy as jnp
+import numpy as np
+import optax
+from datasets import load_dataset
+from flax import struct, traverse_util
+from flax.jax_utils import pad_shard_unpad, replicate, unreplicate
+from flax.training import train_state
+from flax.training.common_utils import get_metrics, onehot, shard
+from huggingface_hub import HfApi
+from tqdm import tqdm
+from utils_qa import postprocess_qa_predictions
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoTokenizer,
+ EvalPrediction,
+ FlaxAutoModelForQuestionAnswering,
+ HfArgumentParser,
+ PreTrainedTokenizerFast,
+ is_tensorboard_available,
+)
+from transformers.utils import check_min_version, send_example_telemetry
+
+
+logger = logging.getLogger(__name__)
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+Array = Any
+Dataset = datasets.arrow_dataset.Dataset
+PRNGKey = Any
+
+
+# region Arguments
+@dataclass
+class TrainingArguments:
+ output_dir: str = field(
+ metadata={"help": "The output directory where the model predictions and checkpoints will be written."},
+ )
+ overwrite_output_dir: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Overwrite the content of the output directory. "
+ "Use this to continue training if output_dir points to a checkpoint directory."
+ )
+ },
+ )
+ do_train: bool = field(default=False, metadata={"help": "Whether to run training."})
+ do_eval: bool = field(default=False, metadata={"help": "Whether to run eval on the dev set."})
+ do_predict: bool = field(default=False, metadata={"help": "Whether to run predictions on the test set."})
+ per_device_train_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for training."}
+ )
+ per_device_eval_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for evaluation."}
+ )
+ learning_rate: float = field(default=5e-5, metadata={"help": "The initial learning rate for AdamW."})
+ weight_decay: float = field(default=0.0, metadata={"help": "Weight decay for AdamW if we apply some."})
+ adam_beta1: float = field(default=0.9, metadata={"help": "Beta1 for AdamW optimizer"})
+ adam_beta2: float = field(default=0.999, metadata={"help": "Beta2 for AdamW optimizer"})
+ adam_epsilon: float = field(default=1e-8, metadata={"help": "Epsilon for AdamW optimizer."})
+ adafactor: bool = field(default=False, metadata={"help": "Whether or not to replace AdamW by Adafactor."})
+ num_train_epochs: float = field(default=3.0, metadata={"help": "Total number of training epochs to perform."})
+ warmup_steps: int = field(default=0, metadata={"help": "Linear warmup over warmup_steps."})
+ logging_steps: int = field(default=500, metadata={"help": "Log every X updates steps."})
+ save_steps: int = field(default=500, metadata={"help": "Save checkpoint every X updates steps."})
+ eval_steps: int = field(default=None, metadata={"help": "Run an evaluation every X steps."})
+ seed: int = field(default=42, metadata={"help": "Random seed that will be set at the beginning of training."})
+ push_to_hub: bool = field(
+ default=False, metadata={"help": "Whether or not to upload the trained model to the model hub after training."}
+ )
+ hub_model_id: str = field(
+ default=None, metadata={"help": "The name of the repository to keep in sync with the local `output_dir`."}
+ )
+ hub_token: str = field(default=None, metadata={"help": "The token to use to push to the Model Hub."})
+
+ def __post_init__(self):
+ if self.output_dir is not None:
+ self.output_dir = os.path.expanduser(self.output_dir)
+
+ def to_dict(self):
+ """
+ Serializes this instance while replace `Enum` by their values (for JSON serialization support). It obfuscates
+ the token values by removing their value.
+ """
+ d = asdict(self)
+ for k, v in d.items():
+ if isinstance(v, Enum):
+ d[k] = v.value
+ if isinstance(v, list) and len(v) > 0 and isinstance(v[0], Enum):
+ d[k] = [x.value for x in v]
+ if k.endswith("_token"):
+ d[k] = f"<{k.upper()}>"
+ return d
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Path to directory to store the pretrained models downloaded from huggingface.co"},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ dtype: Optional[str] = field(
+ default="float32",
+ metadata={
+ "help": (
+ "Floating-point format in which the model weights should be initialized and trained. Choose one of"
+ " `[float32, float16, bfloat16]`."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ test_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input test data file to evaluate the perplexity on (a text file)."},
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ max_seq_length: int = field(
+ default=384,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ pad_to_max_length: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to pad all samples to `max_seq_length`. If False, will pad the samples dynamically when"
+ " batching to the maximum length in the batch (which can be faster on GPU but will be slower on TPU)."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_predict_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of prediction examples to this "
+ "value if set."
+ )
+ },
+ )
+ version_2_with_negative: bool = field(
+ default=False, metadata={"help": "If true, some of the examples do not have an answer."}
+ )
+ null_score_diff_threshold: float = field(
+ default=0.0,
+ metadata={
+ "help": (
+ "The threshold used to select the null answer: if the best answer has a score that is less than "
+ "the score of the null answer minus this threshold, the null answer is selected for this example. "
+ "Only useful when `version_2_with_negative=True`."
+ )
+ },
+ )
+ doc_stride: int = field(
+ default=128,
+ metadata={"help": "When splitting up a long document into chunks, how much stride to take between chunks."},
+ )
+ n_best_size: int = field(
+ default=20,
+ metadata={"help": "The total number of n-best predictions to generate when looking for an answer."},
+ )
+ max_answer_length: int = field(
+ default=30,
+ metadata={
+ "help": (
+ "The maximum length of an answer that can be generated. This is needed because the start "
+ "and end predictions are not conditioned on one another."
+ )
+ },
+ )
+
+ def __post_init__(self):
+ if (
+ self.dataset_name is None
+ and self.train_file is None
+ and self.validation_file is None
+ and self.test_file is None
+ ):
+ raise ValueError("Need either a dataset name or a training/validation file/test_file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+ if self.test_file is not None:
+ extension = self.test_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`test_file` should be a csv or a json file."
+
+
+# endregion
+
+
+# region Create a train state
+def create_train_state(
+ model: FlaxAutoModelForQuestionAnswering,
+ learning_rate_fn: Callable[[int], float],
+ num_labels: int,
+ training_args: TrainingArguments,
+) -> train_state.TrainState:
+ """Create initial training state."""
+
+ class TrainState(train_state.TrainState):
+ """Train state with an Optax optimizer.
+
+ The two functions below differ depending on whether the task is classification
+ or regression.
+
+ Args:
+ logits_fn: Applied to last layer to obtain the logits.
+ loss_fn: Function to compute the loss.
+ """
+
+ logits_fn: Callable = struct.field(pytree_node=False)
+ loss_fn: Callable = struct.field(pytree_node=False)
+
+ # We use Optax's "masking" functionality to not apply weight decay
+ # to bias and LayerNorm scale parameters. decay_mask_fn returns a
+ # mask boolean with the same structure as the parameters.
+ # The mask is True for parameters that should be decayed.
+ def decay_mask_fn(params):
+ flat_params = traverse_util.flatten_dict(params)
+ # find out all LayerNorm parameters
+ layer_norm_candidates = ["layernorm", "layer_norm", "ln"]
+ layer_norm_named_params = {
+ layer[-2:]
+ for layer_norm_name in layer_norm_candidates
+ for layer in flat_params.keys()
+ if layer_norm_name in "".join(layer).lower()
+ }
+ flat_mask = {path: (path[-1] != "bias" and path[-2:] not in layer_norm_named_params) for path in flat_params}
+ return traverse_util.unflatten_dict(flat_mask)
+
+ tx = optax.adamw(
+ learning_rate=learning_rate_fn,
+ b1=training_args.adam_beta1,
+ b2=training_args.adam_beta2,
+ eps=training_args.adam_epsilon,
+ weight_decay=training_args.weight_decay,
+ mask=decay_mask_fn,
+ )
+
+ def cross_entropy_loss(logits, labels):
+ start_loss = optax.softmax_cross_entropy(logits[0], onehot(labels[0], num_classes=num_labels))
+ end_loss = optax.softmax_cross_entropy(logits[1], onehot(labels[1], num_classes=num_labels))
+ xentropy = (start_loss + end_loss) / 2.0
+ return jnp.mean(xentropy)
+
+ return TrainState.create(
+ apply_fn=model.__call__,
+ params=model.params,
+ tx=tx,
+ logits_fn=lambda logits: logits,
+ loss_fn=cross_entropy_loss,
+ )
+
+
+# endregion
+
+
+# region Create learning rate function
+def create_learning_rate_fn(
+ train_ds_size: int, train_batch_size: int, num_train_epochs: int, num_warmup_steps: int, learning_rate: float
+) -> Callable[[int], jnp.ndarray]:
+ """Returns a linear warmup, linear_decay learning rate function."""
+ steps_per_epoch = train_ds_size // train_batch_size
+ num_train_steps = steps_per_epoch * num_train_epochs
+ warmup_fn = optax.linear_schedule(init_value=0.0, end_value=learning_rate, transition_steps=num_warmup_steps)
+ decay_fn = optax.linear_schedule(
+ init_value=learning_rate, end_value=0, transition_steps=num_train_steps - num_warmup_steps
+ )
+ schedule_fn = optax.join_schedules(schedules=[warmup_fn, decay_fn], boundaries=[num_warmup_steps])
+ return schedule_fn
+
+
+# endregion
+
+
+# region train data iterator
+def train_data_collator(rng: PRNGKey, dataset: Dataset, batch_size: int):
+ """Returns shuffled batches of size `batch_size` from truncated `train dataset`, sharded over all local devices."""
+ steps_per_epoch = len(dataset) // batch_size
+ perms = jax.random.permutation(rng, len(dataset))
+ perms = perms[: steps_per_epoch * batch_size] # Skip incomplete batch.
+ perms = perms.reshape((steps_per_epoch, batch_size))
+
+ for perm in perms:
+ batch = dataset[perm]
+ batch = {k: np.array(v) for k, v in batch.items()}
+ batch = shard(batch)
+
+ yield batch
+
+
+# endregion
+
+
+# region eval data iterator
+def eval_data_collator(dataset: Dataset, batch_size: int):
+ """Returns batches of size `batch_size` from `eval dataset`. Sharding handled by `pad_shard_unpad` in the eval loop."""
+ batch_idx = np.arange(len(dataset))
+
+ steps_per_epoch = math.ceil(len(dataset) / batch_size)
+ batch_idx = np.array_split(batch_idx, steps_per_epoch)
+
+ for idx in batch_idx:
+ batch = dataset[idx]
+ # Ignore `offset_mapping` to avoid numpy/JAX array conversion issue.
+ batch = {k: np.array(v) for k, v in batch.items() if k != "offset_mapping"}
+
+ yield batch
+
+
+# endregion
+
+
+def main():
+ # region Argument parsing
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_qa", model_args, data_args, framework="flax")
+ # endregion
+
+ # region Logging
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ # Setup logging, we only want one process per machine to log things on the screen.
+ logger.setLevel(logging.INFO if jax.process_index() == 0 else logging.ERROR)
+ if jax.process_index() == 0:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+ # endregion
+
+ # Handle the repository creation
+ if training_args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = training_args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(training_args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=training_args.hub_token).repo_id
+
+ # region Load Data
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ # Loading the dataset from local csv or json file.
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ if data_args.test_file is not None:
+ data_files["test"] = data_args.test_file
+ extension = data_args.test_file.split(".")[-1]
+ raw_datasets = load_dataset(
+ extension,
+ data_files=data_files,
+ field="data",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+ # endregion
+
+ # region Load pretrained model and tokenizer
+ #
+ # Load pretrained model and tokenizer
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=True,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ # endregion
+
+ # region Tokenizer check: this script requires a fast tokenizer.
+ if not isinstance(tokenizer, PreTrainedTokenizerFast):
+ raise ValueError(
+ "This example script only works for models that have a fast tokenizer. Checkout the big table of models at"
+ " https://huggingface.co/transformers/index.html#supported-frameworks to find the model types that meet"
+ " this requirement"
+ )
+ # endregion
+
+ # region Preprocessing the datasets
+ # Preprocessing is slightly different for training and evaluation.
+ if training_args.do_train:
+ column_names = raw_datasets["train"].column_names
+ elif training_args.do_eval:
+ column_names = raw_datasets["validation"].column_names
+ else:
+ column_names = raw_datasets["test"].column_names
+ question_column_name = "question" if "question" in column_names else column_names[0]
+ context_column_name = "context" if "context" in column_names else column_names[1]
+ answer_column_name = "answers" if "answers" in column_names else column_names[2]
+
+ # Padding side determines if we do (question|context) or (context|question).
+ pad_on_right = tokenizer.padding_side == "right"
+
+ if data_args.max_seq_length > tokenizer.model_max_length:
+ logger.warning(
+ f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
+ f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
+ )
+ max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
+
+ # Training preprocessing
+ def prepare_train_features(examples):
+ # Some of the questions have lots of whitespace on the left, which is not useful and will make the
+ # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
+ # left whitespace
+ examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
+
+ # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
+ # in one example possible giving several features when a context is long, each of those features having a
+ # context that overlaps a bit the context of the previous feature.
+ tokenized_examples = tokenizer(
+ examples[question_column_name if pad_on_right else context_column_name],
+ examples[context_column_name if pad_on_right else question_column_name],
+ truncation="only_second" if pad_on_right else "only_first",
+ max_length=max_seq_length,
+ stride=data_args.doc_stride,
+ return_overflowing_tokens=True,
+ return_offsets_mapping=True,
+ padding="max_length",
+ )
+
+ # Since one example might give us several features if it has a long context, we need a map from a feature to
+ # its corresponding example. This key gives us just that.
+ sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
+ # The offset mappings will give us a map from token to character position in the original context. This will
+ # help us compute the start_positions and end_positions.
+ offset_mapping = tokenized_examples.pop("offset_mapping")
+
+ # Let's label those examples!
+ tokenized_examples["start_positions"] = []
+ tokenized_examples["end_positions"] = []
+
+ for i, offsets in enumerate(offset_mapping):
+ # We will label impossible answers with the index of the CLS token.
+ input_ids = tokenized_examples["input_ids"][i]
+ cls_index = input_ids.index(tokenizer.cls_token_id)
+
+ # Grab the sequence corresponding to that example (to know what is the context and what is the question).
+ sequence_ids = tokenized_examples.sequence_ids(i)
+
+ # One example can give several spans, this is the index of the example containing this span of text.
+ sample_index = sample_mapping[i]
+ answers = examples[answer_column_name][sample_index]
+ # If no answers are given, set the cls_index as answer.
+ if len(answers["answer_start"]) == 0:
+ tokenized_examples["start_positions"].append(cls_index)
+ tokenized_examples["end_positions"].append(cls_index)
+ else:
+ # Start/end character index of the answer in the text.
+ start_char = answers["answer_start"][0]
+ end_char = start_char + len(answers["text"][0])
+
+ # Start token index of the current span in the text.
+ token_start_index = 0
+ while sequence_ids[token_start_index] != (1 if pad_on_right else 0):
+ token_start_index += 1
+
+ # End token index of the current span in the text.
+ token_end_index = len(input_ids) - 1
+ while sequence_ids[token_end_index] != (1 if pad_on_right else 0):
+ token_end_index -= 1
+
+ # Detect if the answer is out of the span (in which case this feature is labeled with the CLS index).
+ if not (offsets[token_start_index][0] <= start_char and offsets[token_end_index][1] >= end_char):
+ tokenized_examples["start_positions"].append(cls_index)
+ tokenized_examples["end_positions"].append(cls_index)
+ else:
+ # Otherwise move the token_start_index and token_end_index to the two ends of the answer.
+ # Note: we could go after the last offset if the answer is the last word (edge case).
+ while token_start_index < len(offsets) and offsets[token_start_index][0] <= start_char:
+ token_start_index += 1
+ tokenized_examples["start_positions"].append(token_start_index - 1)
+ while offsets[token_end_index][1] >= end_char:
+ token_end_index -= 1
+ tokenized_examples["end_positions"].append(token_end_index + 1)
+
+ return tokenized_examples
+
+ processed_raw_datasets = {}
+ if training_args.do_train:
+ if "train" not in raw_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = raw_datasets["train"]
+ if data_args.max_train_samples is not None:
+ # We will select sample from whole data if argument is specified
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+ # Create train feature from dataset
+ train_dataset = train_dataset.map(
+ prepare_train_features,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ )
+ if data_args.max_train_samples is not None:
+ # Number of samples might increase during Feature Creation, We select only specified max samples
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+ processed_raw_datasets["train"] = train_dataset
+
+ # Validation preprocessing
+ def prepare_validation_features(examples):
+ # Some of the questions have lots of whitespace on the left, which is not useful and will make the
+ # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
+ # left whitespace
+ examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
+
+ # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
+ # in one example possible giving several features when a context is long, each of those features having a
+ # context that overlaps a bit the context of the previous feature.
+ tokenized_examples = tokenizer(
+ examples[question_column_name if pad_on_right else context_column_name],
+ examples[context_column_name if pad_on_right else question_column_name],
+ truncation="only_second" if pad_on_right else "only_first",
+ max_length=max_seq_length,
+ stride=data_args.doc_stride,
+ return_overflowing_tokens=True,
+ return_offsets_mapping=True,
+ padding="max_length",
+ )
+
+ # Since one example might give us several features if it has a long context, we need a map from a feature to
+ # its corresponding example. This key gives us just that.
+ sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
+
+ # For evaluation, we will need to convert our predictions to substrings of the context, so we keep the
+ # corresponding example_id and we will store the offset mappings.
+ tokenized_examples["example_id"] = []
+
+ for i in range(len(tokenized_examples["input_ids"])):
+ # Grab the sequence corresponding to that example (to know what is the context and what is the question).
+ sequence_ids = tokenized_examples.sequence_ids(i)
+ context_index = 1 if pad_on_right else 0
+
+ # One example can give several spans, this is the index of the example containing this span of text.
+ sample_index = sample_mapping[i]
+ tokenized_examples["example_id"].append(examples["id"][sample_index])
+
+ # Set to None the offset_mapping that are not part of the context so it's easy to determine if a token
+ # position is part of the context or not.
+ tokenized_examples["offset_mapping"][i] = [
+ (o if sequence_ids[k] == context_index else None)
+ for k, o in enumerate(tokenized_examples["offset_mapping"][i])
+ ]
+
+ return tokenized_examples
+
+ if training_args.do_eval:
+ if "validation" not in raw_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_examples = raw_datasets["validation"]
+ if data_args.max_eval_samples is not None:
+ # We will select sample from whole data
+ max_eval_samples = min(len(eval_examples), data_args.max_eval_samples)
+ eval_examples = eval_examples.select(range(max_eval_samples))
+ # Validation Feature Creation
+ eval_dataset = eval_examples.map(
+ prepare_validation_features,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ )
+ if data_args.max_eval_samples is not None:
+ # During Feature creation dataset samples might increase, we will select required samples again
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+ processed_raw_datasets["validation"] = eval_dataset
+
+ if training_args.do_predict:
+ if "test" not in raw_datasets:
+ raise ValueError("--do_predict requires a test dataset")
+ predict_examples = raw_datasets["test"]
+ if data_args.max_predict_samples is not None:
+ # We will select sample from whole data
+ predict_examples = predict_examples.select(range(data_args.max_predict_samples))
+ # Predict Feature Creation
+ predict_dataset = predict_examples.map(
+ prepare_validation_features,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ )
+ if data_args.max_predict_samples is not None:
+ # During Feature creation dataset samples might increase, we will select required samples again
+ max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
+ predict_dataset = predict_dataset.select(range(max_predict_samples))
+ processed_raw_datasets["test"] = predict_dataset
+ # endregion
+
+ # region Metrics and Post-processing:
+ def post_processing_function(examples, features, predictions, stage="eval"):
+ # Post-processing: we match the start logits and end logits to answers in the original context.
+ predictions = postprocess_qa_predictions(
+ examples=examples,
+ features=features,
+ predictions=predictions,
+ version_2_with_negative=data_args.version_2_with_negative,
+ n_best_size=data_args.n_best_size,
+ max_answer_length=data_args.max_answer_length,
+ null_score_diff_threshold=data_args.null_score_diff_threshold,
+ output_dir=training_args.output_dir,
+ prefix=stage,
+ )
+ # Format the result to the format the metric expects.
+ if data_args.version_2_with_negative:
+ formatted_predictions = [
+ {"id": k, "prediction_text": v, "no_answer_probability": 0.0} for k, v in predictions.items()
+ ]
+ else:
+ formatted_predictions = [{"id": k, "prediction_text": v} for k, v in predictions.items()]
+
+ references = [{"id": ex["id"], "answers": ex[answer_column_name]} for ex in examples]
+ return EvalPrediction(predictions=formatted_predictions, label_ids=references)
+
+ metric = evaluate.load(
+ "squad_v2" if data_args.version_2_with_negative else "squad", cache_dir=model_args.cache_dir
+ )
+
+ def compute_metrics(p: EvalPrediction):
+ return metric.compute(predictions=p.predictions, references=p.label_ids)
+
+ # Create and fill numpy array of size len_of_validation_data * max_length_of_output_tensor
+ def create_and_fill_np_array(start_or_end_logits, dataset, max_len):
+ """
+ Create and fill numpy array of size len_of_validation_data * max_length_of_output_tensor
+
+ Args:
+ start_or_end_logits(:obj:`tensor`):
+ This is the output predictions of the model. We can only enter either start or end logits.
+ eval_dataset: Evaluation dataset
+ max_len(:obj:`int`):
+ The maximum length of the output tensor. ( See the model.eval() part for more details )
+ """
+
+ step = 0
+ # create a numpy array and fill it with -100.
+ logits_concat = np.full((len(dataset), max_len), -100, dtype=np.float64)
+ # Now since we have create an array now we will populate it with the outputs of the model.
+ for i, output_logit in enumerate(start_or_end_logits): # populate columns
+ # We have to fill it such that we have to take the whole tensor and replace it on the newly created array
+ # And after every iteration we have to change the step
+
+ batch_size = output_logit.shape[0]
+ cols = output_logit.shape[1]
+
+ if step + batch_size < len(dataset):
+ logits_concat[step : step + batch_size, :cols] = output_logit
+ else:
+ logits_concat[step:, :cols] = output_logit[: len(dataset) - step]
+
+ step += batch_size
+
+ return logits_concat
+
+ # endregion
+
+ # region Training steps and logging init
+ train_dataset = processed_raw_datasets["train"]
+ eval_dataset = processed_raw_datasets["validation"]
+
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ # Define a summary writer
+ has_tensorboard = is_tensorboard_available()
+ if has_tensorboard and jax.process_index() == 0:
+ try:
+ from flax.metrics.tensorboard import SummaryWriter
+
+ summary_writer = SummaryWriter(training_args.output_dir)
+ summary_writer.hparams({**training_args.to_dict(), **vars(model_args), **vars(data_args)})
+ except ImportError as ie:
+ has_tensorboard = False
+ logger.warning(
+ f"Unable to display metrics through TensorBoard because some package are not installed: {ie}"
+ )
+ else:
+ logger.warning(
+ "Unable to display metrics through TensorBoard because the package is not installed: "
+ "Please run pip install tensorboard to enable."
+ )
+
+ def write_train_metric(summary_writer, train_metrics, train_time, step):
+ summary_writer.scalar("train_time", train_time, step)
+
+ train_metrics = get_metrics(train_metrics)
+ for key, vals in train_metrics.items():
+ tag = f"train_{key}"
+ for i, val in enumerate(vals):
+ summary_writer.scalar(tag, val, step - len(vals) + i + 1)
+
+ def write_eval_metric(summary_writer, eval_metrics, step):
+ for metric_name, value in eval_metrics.items():
+ summary_writer.scalar(f"eval_{metric_name}", value, step)
+
+ num_epochs = int(training_args.num_train_epochs)
+ rng = jax.random.PRNGKey(training_args.seed)
+ dropout_rngs = jax.random.split(rng, jax.local_device_count())
+
+ train_batch_size = int(training_args.per_device_train_batch_size) * jax.local_device_count()
+ per_device_eval_batch_size = int(training_args.per_device_eval_batch_size)
+ eval_batch_size = per_device_eval_batch_size * jax.local_device_count()
+ # endregion
+
+ # region Load model
+ model = FlaxAutoModelForQuestionAnswering.from_pretrained(
+ model_args.model_name_or_path,
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ seed=training_args.seed,
+ dtype=getattr(jnp, model_args.dtype),
+ )
+
+ learning_rate_fn = create_learning_rate_fn(
+ len(train_dataset),
+ train_batch_size,
+ training_args.num_train_epochs,
+ training_args.warmup_steps,
+ training_args.learning_rate,
+ )
+
+ state = create_train_state(model, learning_rate_fn, num_labels=max_seq_length, training_args=training_args)
+ # endregion
+
+ # region Define train step functions
+ def train_step(
+ state: train_state.TrainState, batch: Dict[str, Array], dropout_rng: PRNGKey
+ ) -> Tuple[train_state.TrainState, float]:
+ """Trains model with an optimizer (both in `state`) on `batch`, returning a pair `(new_state, loss)`."""
+ dropout_rng, new_dropout_rng = jax.random.split(dropout_rng)
+ start_positions = batch.pop("start_positions")
+ end_positions = batch.pop("end_positions")
+ targets = (start_positions, end_positions)
+
+ def loss_fn(params):
+ logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)
+ loss = state.loss_fn(logits, targets)
+ return loss
+
+ grad_fn = jax.value_and_grad(loss_fn)
+ loss, grad = grad_fn(state.params)
+ grad = jax.lax.pmean(grad, "batch")
+ new_state = state.apply_gradients(grads=grad)
+ metrics = jax.lax.pmean({"loss": loss, "learning_rate": learning_rate_fn(state.step)}, axis_name="batch")
+ return new_state, metrics, new_dropout_rng
+
+ p_train_step = jax.pmap(train_step, axis_name="batch", donate_argnums=(0,))
+ # endregion
+
+ # region Define eval step functions
+ def eval_step(state, batch):
+ logits = state.apply_fn(**batch, params=state.params, train=False)
+ return state.logits_fn(logits)
+
+ p_eval_step = jax.pmap(eval_step, axis_name="batch")
+ # endregion
+
+ # region Define train and eval loop
+ logger.info(f"===== Starting training ({num_epochs} epochs) =====")
+ train_time = 0
+
+ # make sure weights are replicated on each device
+ state = replicate(state)
+
+ train_time = 0
+ step_per_epoch = len(train_dataset) // train_batch_size
+ total_steps = step_per_epoch * num_epochs
+ epochs = tqdm(range(num_epochs), desc=f"Epoch ... (1/{num_epochs})", position=0)
+ for epoch in epochs:
+ train_start = time.time()
+ train_metrics = []
+
+ # Create sampling rng
+ rng, input_rng = jax.random.split(rng)
+
+ # train
+ for step, batch in enumerate(
+ tqdm(
+ train_data_collator(input_rng, train_dataset, train_batch_size),
+ total=step_per_epoch,
+ desc="Training...",
+ position=1,
+ ),
+ 1,
+ ):
+ state, train_metric, dropout_rngs = p_train_step(state, batch, dropout_rngs)
+ train_metrics.append(train_metric)
+
+ cur_step = epoch * step_per_epoch + step
+
+ if cur_step % training_args.logging_steps == 0 and cur_step > 0:
+ # Save metrics
+ train_metric = unreplicate(train_metric)
+ train_time += time.time() - train_start
+ if has_tensorboard and jax.process_index() == 0:
+ write_train_metric(summary_writer, train_metrics, train_time, cur_step)
+
+ epochs.write(
+ f"Step... ({cur_step}/{total_steps} | Training Loss: {train_metric['loss']}, Learning Rate:"
+ f" {train_metric['learning_rate']})"
+ )
+
+ train_metrics = []
+
+ if (
+ training_args.do_eval
+ and (cur_step % training_args.eval_steps == 0 or cur_step % step_per_epoch == 0)
+ and cur_step > 0
+ ):
+ eval_metrics = {}
+ all_start_logits = []
+ all_end_logits = []
+ # evaluate
+ for batch in tqdm(
+ eval_data_collator(eval_dataset, eval_batch_size),
+ total=math.ceil(len(eval_dataset) / eval_batch_size),
+ desc="Evaluating ...",
+ position=2,
+ ):
+ _ = batch.pop("example_id")
+ predictions = pad_shard_unpad(p_eval_step)(
+ state, batch, min_device_batch=per_device_eval_batch_size
+ )
+ start_logits = np.array(predictions[0])
+ end_logits = np.array(predictions[1])
+ all_start_logits.append(start_logits)
+ all_end_logits.append(end_logits)
+
+ max_len = max([x.shape[1] for x in all_start_logits]) # Get the max_length of the tensor
+
+ # concatenate the numpy array
+ start_logits_concat = create_and_fill_np_array(all_start_logits, eval_dataset, max_len)
+ end_logits_concat = create_and_fill_np_array(all_end_logits, eval_dataset, max_len)
+
+ # delete the list of numpy arrays
+ del all_start_logits
+ del all_end_logits
+ outputs_numpy = (start_logits_concat, end_logits_concat)
+ prediction = post_processing_function(eval_examples, eval_dataset, outputs_numpy)
+ eval_metrics = compute_metrics(prediction)
+
+ logger.info(f"Step... ({cur_step}/{total_steps} | Evaluation metrics: {eval_metrics})")
+
+ if has_tensorboard and jax.process_index() == 0:
+ write_eval_metric(summary_writer, eval_metrics, cur_step)
+
+ if (cur_step % training_args.save_steps == 0 and cur_step > 0) or (cur_step == total_steps):
+ # save checkpoint after each epoch and push checkpoint to the hub
+ if jax.process_index() == 0:
+ params = jax.device_get(unreplicate(state.params))
+ model.save_pretrained(training_args.output_dir, params=params)
+ tokenizer.save_pretrained(training_args.output_dir)
+ if training_args.push_to_hub:
+ api.upload_folder(
+ commit_message=f"Saving weights and logs of step {cur_step}",
+ folder_path=training_args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=training_args.hub_token,
+ )
+ epochs.desc = f"Epoch ... {epoch + 1}/{num_epochs}"
+ # endregion
+
+ # Eval after training
+ if training_args.do_eval:
+ eval_metrics = {}
+ all_start_logits = []
+ all_end_logits = []
+
+ eval_loader = eval_data_collator(eval_dataset, eval_batch_size)
+ for batch in tqdm(
+ eval_loader, total=math.ceil(len(eval_dataset) / eval_batch_size), desc="Evaluating ...", position=2
+ ):
+ _ = batch.pop("example_id")
+ predictions = pad_shard_unpad(p_eval_step)(state, batch, min_device_batch=per_device_eval_batch_size)
+ start_logits = np.array(predictions[0])
+ end_logits = np.array(predictions[1])
+ all_start_logits.append(start_logits)
+ all_end_logits.append(end_logits)
+
+ max_len = max([x.shape[1] for x in all_start_logits]) # Get the max_length of the tensor
+
+ # concatenate the numpy array
+ start_logits_concat = create_and_fill_np_array(all_start_logits, eval_dataset, max_len)
+ end_logits_concat = create_and_fill_np_array(all_end_logits, eval_dataset, max_len)
+
+ # delete the list of numpy arrays
+ del all_start_logits
+ del all_end_logits
+ outputs_numpy = (start_logits_concat, end_logits_concat)
+ prediction = post_processing_function(eval_examples, eval_dataset, outputs_numpy)
+ eval_metrics = compute_metrics(prediction)
+
+ if jax.process_index() == 0:
+ eval_metrics = {f"eval_{metric_name}": value for metric_name, value in eval_metrics.items()}
+ path = os.path.join(training_args.output_dir, "eval_results.json")
+ with open(path, "w") as f:
+ json.dump(eval_metrics, f, indent=4, sort_keys=True)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/question-answering/utils_qa.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/question-answering/utils_qa.py
new file mode 100644
index 0000000000000000000000000000000000000000..79497dbb816ed2bf3d33e131abecd1aa6caf6027
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/question-answering/utils_qa.py
@@ -0,0 +1,444 @@
+# coding=utf-8
+# Copyright 2020 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Post-processing utilities for question answering.
+"""
+
+import collections
+import json
+import logging
+import os
+from typing import Optional, Tuple
+
+import numpy as np
+from tqdm.auto import tqdm
+
+
+logger = logging.getLogger(__name__)
+
+
+def postprocess_qa_predictions(
+ examples,
+ features,
+ predictions: Tuple[np.ndarray, np.ndarray],
+ version_2_with_negative: bool = False,
+ n_best_size: int = 20,
+ max_answer_length: int = 30,
+ null_score_diff_threshold: float = 0.0,
+ output_dir: Optional[str] = None,
+ prefix: Optional[str] = None,
+ log_level: Optional[int] = logging.WARNING,
+):
+ """
+ Post-processes the predictions of a question-answering model to convert them to answers that are substrings of the
+ original contexts. This is the base postprocessing functions for models that only return start and end logits.
+
+ Args:
+ examples: The non-preprocessed dataset (see the main script for more information).
+ features: The processed dataset (see the main script for more information).
+ predictions (:obj:`Tuple[np.ndarray, np.ndarray]`):
+ The predictions of the model: two arrays containing the start logits and the end logits respectively. Its
+ first dimension must match the number of elements of :obj:`features`.
+ version_2_with_negative (:obj:`bool`, `optional`, defaults to :obj:`False`):
+ Whether or not the underlying dataset contains examples with no answers.
+ n_best_size (:obj:`int`, `optional`, defaults to 20):
+ The total number of n-best predictions to generate when looking for an answer.
+ max_answer_length (:obj:`int`, `optional`, defaults to 30):
+ The maximum length of an answer that can be generated. This is needed because the start and end predictions
+ are not conditioned on one another.
+ null_score_diff_threshold (:obj:`float`, `optional`, defaults to 0):
+ The threshold used to select the null answer: if the best answer has a score that is less than the score of
+ the null answer minus this threshold, the null answer is selected for this example (note that the score of
+ the null answer for an example giving several features is the minimum of the scores for the null answer on
+ each feature: all features must be aligned on the fact they `want` to predict a null answer).
+
+ Only useful when :obj:`version_2_with_negative` is :obj:`True`.
+ output_dir (:obj:`str`, `optional`):
+ If provided, the dictionaries of predictions, n_best predictions (with their scores and logits) and, if
+ :obj:`version_2_with_negative=True`, the dictionary of the scores differences between best and null
+ answers, are saved in `output_dir`.
+ prefix (:obj:`str`, `optional`):
+ If provided, the dictionaries mentioned above are saved with `prefix` added to their names.
+ log_level (:obj:`int`, `optional`, defaults to ``logging.WARNING``):
+ ``logging`` log level (e.g., ``logging.WARNING``)
+ """
+ if len(predictions) != 2:
+ raise ValueError("`predictions` should be a tuple with two elements (start_logits, end_logits).")
+ all_start_logits, all_end_logits = predictions
+
+ if len(predictions[0]) != len(features):
+ raise ValueError(f"Got {len(predictions[0])} predictions and {len(features)} features.")
+
+ # Build a map example to its corresponding features.
+ example_id_to_index = {k: i for i, k in enumerate(examples["id"])}
+ features_per_example = collections.defaultdict(list)
+ for i, feature in enumerate(features):
+ features_per_example[example_id_to_index[feature["example_id"]]].append(i)
+
+ # The dictionaries we have to fill.
+ all_predictions = collections.OrderedDict()
+ all_nbest_json = collections.OrderedDict()
+ if version_2_with_negative:
+ scores_diff_json = collections.OrderedDict()
+
+ # Logging.
+ logger.setLevel(log_level)
+ logger.info(f"Post-processing {len(examples)} example predictions split into {len(features)} features.")
+
+ # Let's loop over all the examples!
+ for example_index, example in enumerate(tqdm(examples)):
+ # Those are the indices of the features associated to the current example.
+ feature_indices = features_per_example[example_index]
+
+ min_null_prediction = None
+ prelim_predictions = []
+
+ # Looping through all the features associated to the current example.
+ for feature_index in feature_indices:
+ # We grab the predictions of the model for this feature.
+ start_logits = all_start_logits[feature_index]
+ end_logits = all_end_logits[feature_index]
+ # This is what will allow us to map some the positions in our logits to span of texts in the original
+ # context.
+ offset_mapping = features[feature_index]["offset_mapping"]
+ # Optional `token_is_max_context`, if provided we will remove answers that do not have the maximum context
+ # available in the current feature.
+ token_is_max_context = features[feature_index].get("token_is_max_context", None)
+
+ # Update minimum null prediction.
+ feature_null_score = start_logits[0] + end_logits[0]
+ if min_null_prediction is None or min_null_prediction["score"] > feature_null_score:
+ min_null_prediction = {
+ "offsets": (0, 0),
+ "score": feature_null_score,
+ "start_logit": start_logits[0],
+ "end_logit": end_logits[0],
+ }
+
+ # Go through all possibilities for the `n_best_size` greater start and end logits.
+ start_indexes = np.argsort(start_logits)[-1 : -n_best_size - 1 : -1].tolist()
+ end_indexes = np.argsort(end_logits)[-1 : -n_best_size - 1 : -1].tolist()
+ for start_index in start_indexes:
+ for end_index in end_indexes:
+ # Don't consider out-of-scope answers, either because the indices are out of bounds or correspond
+ # to part of the input_ids that are not in the context.
+ if (
+ start_index >= len(offset_mapping)
+ or end_index >= len(offset_mapping)
+ or offset_mapping[start_index] is None
+ or len(offset_mapping[start_index]) < 2
+ or offset_mapping[end_index] is None
+ or len(offset_mapping[end_index]) < 2
+ ):
+ continue
+ # Don't consider answers with a length that is either < 0 or > max_answer_length.
+ if end_index < start_index or end_index - start_index + 1 > max_answer_length:
+ continue
+ # Don't consider answer that don't have the maximum context available (if such information is
+ # provided).
+ if token_is_max_context is not None and not token_is_max_context.get(str(start_index), False):
+ continue
+
+ prelim_predictions.append(
+ {
+ "offsets": (offset_mapping[start_index][0], offset_mapping[end_index][1]),
+ "score": start_logits[start_index] + end_logits[end_index],
+ "start_logit": start_logits[start_index],
+ "end_logit": end_logits[end_index],
+ }
+ )
+ if version_2_with_negative and min_null_prediction is not None:
+ # Add the minimum null prediction
+ prelim_predictions.append(min_null_prediction)
+ null_score = min_null_prediction["score"]
+
+ # Only keep the best `n_best_size` predictions.
+ predictions = sorted(prelim_predictions, key=lambda x: x["score"], reverse=True)[:n_best_size]
+
+ # Add back the minimum null prediction if it was removed because of its low score.
+ if (
+ version_2_with_negative
+ and min_null_prediction is not None
+ and not any(p["offsets"] == (0, 0) for p in predictions)
+ ):
+ predictions.append(min_null_prediction)
+
+ # Use the offsets to gather the answer text in the original context.
+ context = example["context"]
+ for pred in predictions:
+ offsets = pred.pop("offsets")
+ pred["text"] = context[offsets[0] : offsets[1]]
+
+ # In the very rare edge case we have not a single non-null prediction, we create a fake prediction to avoid
+ # failure.
+ if len(predictions) == 0 or (len(predictions) == 1 and predictions[0]["text"] == ""):
+ predictions.insert(0, {"text": "empty", "start_logit": 0.0, "end_logit": 0.0, "score": 0.0})
+
+ # Compute the softmax of all scores (we do it with numpy to stay independent from torch/tf in this file, using
+ # the LogSumExp trick).
+ scores = np.array([pred.pop("score") for pred in predictions])
+ exp_scores = np.exp(scores - np.max(scores))
+ probs = exp_scores / exp_scores.sum()
+
+ # Include the probabilities in our predictions.
+ for prob, pred in zip(probs, predictions):
+ pred["probability"] = prob
+
+ # Pick the best prediction. If the null answer is not possible, this is easy.
+ if not version_2_with_negative:
+ all_predictions[example["id"]] = predictions[0]["text"]
+ else:
+ # Otherwise we first need to find the best non-empty prediction.
+ i = 0
+ while predictions[i]["text"] == "":
+ i += 1
+ best_non_null_pred = predictions[i]
+
+ # Then we compare to the null prediction using the threshold.
+ score_diff = null_score - best_non_null_pred["start_logit"] - best_non_null_pred["end_logit"]
+ scores_diff_json[example["id"]] = float(score_diff) # To be JSON-serializable.
+ if score_diff > null_score_diff_threshold:
+ all_predictions[example["id"]] = ""
+ else:
+ all_predictions[example["id"]] = best_non_null_pred["text"]
+
+ # Make `predictions` JSON-serializable by casting np.float back to float.
+ all_nbest_json[example["id"]] = [
+ {k: (float(v) if isinstance(v, (np.float16, np.float32, np.float64)) else v) for k, v in pred.items()}
+ for pred in predictions
+ ]
+
+ # If we have an output_dir, let's save all those dicts.
+ if output_dir is not None:
+ if not os.path.isdir(output_dir):
+ raise EnvironmentError(f"{output_dir} is not a directory.")
+
+ prediction_file = os.path.join(
+ output_dir, "predictions.json" if prefix is None else f"{prefix}_predictions.json"
+ )
+ nbest_file = os.path.join(
+ output_dir, "nbest_predictions.json" if prefix is None else f"{prefix}_nbest_predictions.json"
+ )
+ if version_2_with_negative:
+ null_odds_file = os.path.join(
+ output_dir, "null_odds.json" if prefix is None else f"{prefix}_null_odds.json"
+ )
+
+ logger.info(f"Saving predictions to {prediction_file}.")
+ with open(prediction_file, "w") as writer:
+ writer.write(json.dumps(all_predictions, indent=4) + "\n")
+ logger.info(f"Saving nbest_preds to {nbest_file}.")
+ with open(nbest_file, "w") as writer:
+ writer.write(json.dumps(all_nbest_json, indent=4) + "\n")
+ if version_2_with_negative:
+ logger.info(f"Saving null_odds to {null_odds_file}.")
+ with open(null_odds_file, "w") as writer:
+ writer.write(json.dumps(scores_diff_json, indent=4) + "\n")
+
+ return all_predictions
+
+
+def postprocess_qa_predictions_with_beam_search(
+ examples,
+ features,
+ predictions: Tuple[np.ndarray, np.ndarray],
+ version_2_with_negative: bool = False,
+ n_best_size: int = 20,
+ max_answer_length: int = 30,
+ start_n_top: int = 5,
+ end_n_top: int = 5,
+ output_dir: Optional[str] = None,
+ prefix: Optional[str] = None,
+ log_level: Optional[int] = logging.WARNING,
+):
+ """
+ Post-processes the predictions of a question-answering model with beam search to convert them to answers that are substrings of the
+ original contexts. This is the postprocessing functions for models that return start and end logits, indices, as well as
+ cls token predictions.
+
+ Args:
+ examples: The non-preprocessed dataset (see the main script for more information).
+ features: The processed dataset (see the main script for more information).
+ predictions (:obj:`Tuple[np.ndarray, np.ndarray]`):
+ The predictions of the model: two arrays containing the start logits and the end logits respectively. Its
+ first dimension must match the number of elements of :obj:`features`.
+ version_2_with_negative (:obj:`bool`, `optional`, defaults to :obj:`False`):
+ Whether or not the underlying dataset contains examples with no answers.
+ n_best_size (:obj:`int`, `optional`, defaults to 20):
+ The total number of n-best predictions to generate when looking for an answer.
+ max_answer_length (:obj:`int`, `optional`, defaults to 30):
+ The maximum length of an answer that can be generated. This is needed because the start and end predictions
+ are not conditioned on one another.
+ start_n_top (:obj:`int`, `optional`, defaults to 5):
+ The number of top start logits too keep when searching for the :obj:`n_best_size` predictions.
+ end_n_top (:obj:`int`, `optional`, defaults to 5):
+ The number of top end logits too keep when searching for the :obj:`n_best_size` predictions.
+ output_dir (:obj:`str`, `optional`):
+ If provided, the dictionaries of predictions, n_best predictions (with their scores and logits) and, if
+ :obj:`version_2_with_negative=True`, the dictionary of the scores differences between best and null
+ answers, are saved in `output_dir`.
+ prefix (:obj:`str`, `optional`):
+ If provided, the dictionaries mentioned above are saved with `prefix` added to their names.
+ log_level (:obj:`int`, `optional`, defaults to ``logging.WARNING``):
+ ``logging`` log level (e.g., ``logging.WARNING``)
+ """
+ if len(predictions) != 5:
+ raise ValueError("`predictions` should be a tuple with five elements.")
+ start_top_log_probs, start_top_index, end_top_log_probs, end_top_index, cls_logits = predictions
+
+ if len(predictions[0]) != len(features):
+ raise ValueError(f"Got {len(predictions[0])} predictions and {len(features)} features.")
+
+ # Build a map example to its corresponding features.
+ example_id_to_index = {k: i for i, k in enumerate(examples["id"])}
+ features_per_example = collections.defaultdict(list)
+ for i, feature in enumerate(features):
+ features_per_example[example_id_to_index[feature["example_id"]]].append(i)
+
+ # The dictionaries we have to fill.
+ all_predictions = collections.OrderedDict()
+ all_nbest_json = collections.OrderedDict()
+ scores_diff_json = collections.OrderedDict() if version_2_with_negative else None
+
+ # Logging.
+ logger.setLevel(log_level)
+ logger.info(f"Post-processing {len(examples)} example predictions split into {len(features)} features.")
+
+ # Let's loop over all the examples!
+ for example_index, example in enumerate(tqdm(examples)):
+ # Those are the indices of the features associated to the current example.
+ feature_indices = features_per_example[example_index]
+
+ min_null_score = None
+ prelim_predictions = []
+
+ # Looping through all the features associated to the current example.
+ for feature_index in feature_indices:
+ # We grab the predictions of the model for this feature.
+ start_log_prob = start_top_log_probs[feature_index]
+ start_indexes = start_top_index[feature_index]
+ end_log_prob = end_top_log_probs[feature_index]
+ end_indexes = end_top_index[feature_index]
+ feature_null_score = cls_logits[feature_index]
+ # This is what will allow us to map some the positions in our logits to span of texts in the original
+ # context.
+ offset_mapping = features[feature_index]["offset_mapping"]
+ # Optional `token_is_max_context`, if provided we will remove answers that do not have the maximum context
+ # available in the current feature.
+ token_is_max_context = features[feature_index].get("token_is_max_context", None)
+
+ # Update minimum null prediction
+ if min_null_score is None or feature_null_score < min_null_score:
+ min_null_score = feature_null_score
+
+ # Go through all possibilities for the `n_start_top`/`n_end_top` greater start and end logits.
+ for i in range(start_n_top):
+ for j in range(end_n_top):
+ start_index = int(start_indexes[i])
+ j_index = i * end_n_top + j
+ end_index = int(end_indexes[j_index])
+ # Don't consider out-of-scope answers (last part of the test should be unnecessary because of the
+ # p_mask but let's not take any risk)
+ if (
+ start_index >= len(offset_mapping)
+ or end_index >= len(offset_mapping)
+ or offset_mapping[start_index] is None
+ or len(offset_mapping[start_index]) < 2
+ or offset_mapping[end_index] is None
+ or len(offset_mapping[end_index]) < 2
+ ):
+ continue
+
+ # Don't consider answers with a length negative or > max_answer_length.
+ if end_index < start_index or end_index - start_index + 1 > max_answer_length:
+ continue
+ # Don't consider answer that don't have the maximum context available (if such information is
+ # provided).
+ if token_is_max_context is not None and not token_is_max_context.get(str(start_index), False):
+ continue
+ prelim_predictions.append(
+ {
+ "offsets": (offset_mapping[start_index][0], offset_mapping[end_index][1]),
+ "score": start_log_prob[i] + end_log_prob[j_index],
+ "start_log_prob": start_log_prob[i],
+ "end_log_prob": end_log_prob[j_index],
+ }
+ )
+
+ # Only keep the best `n_best_size` predictions.
+ predictions = sorted(prelim_predictions, key=lambda x: x["score"], reverse=True)[:n_best_size]
+
+ # Use the offsets to gather the answer text in the original context.
+ context = example["context"]
+ for pred in predictions:
+ offsets = pred.pop("offsets")
+ pred["text"] = context[offsets[0] : offsets[1]]
+
+ # In the very rare edge case we have not a single non-null prediction, we create a fake prediction to avoid
+ # failure.
+ if len(predictions) == 0:
+ # Without predictions min_null_score is going to be None and None will cause an exception later
+ min_null_score = -2e-6
+ predictions.insert(0, {"text": "", "start_logit": -1e-6, "end_logit": -1e-6, "score": min_null_score})
+
+ # Compute the softmax of all scores (we do it with numpy to stay independent from torch/tf in this file, using
+ # the LogSumExp trick).
+ scores = np.array([pred.pop("score") for pred in predictions])
+ exp_scores = np.exp(scores - np.max(scores))
+ probs = exp_scores / exp_scores.sum()
+
+ # Include the probabilities in our predictions.
+ for prob, pred in zip(probs, predictions):
+ pred["probability"] = prob
+
+ # Pick the best prediction and set the probability for the null answer.
+ all_predictions[example["id"]] = predictions[0]["text"]
+ if version_2_with_negative:
+ scores_diff_json[example["id"]] = float(min_null_score)
+
+ # Make `predictions` JSON-serializable by casting np.float back to float.
+ all_nbest_json[example["id"]] = [
+ {k: (float(v) if isinstance(v, (np.float16, np.float32, np.float64)) else v) for k, v in pred.items()}
+ for pred in predictions
+ ]
+
+ # If we have an output_dir, let's save all those dicts.
+ if output_dir is not None:
+ if not os.path.isdir(output_dir):
+ raise EnvironmentError(f"{output_dir} is not a directory.")
+
+ prediction_file = os.path.join(
+ output_dir, "predictions.json" if prefix is None else f"{prefix}_predictions.json"
+ )
+ nbest_file = os.path.join(
+ output_dir, "nbest_predictions.json" if prefix is None else f"{prefix}_nbest_predictions.json"
+ )
+ if version_2_with_negative:
+ null_odds_file = os.path.join(
+ output_dir, "null_odds.json" if prefix is None else f"{prefix}_null_odds.json"
+ )
+
+ logger.info(f"Saving predictions to {prediction_file}.")
+ with open(prediction_file, "w") as writer:
+ writer.write(json.dumps(all_predictions, indent=4) + "\n")
+ logger.info(f"Saving nbest_preds to {nbest_file}.")
+ with open(nbest_file, "w") as writer:
+ writer.write(json.dumps(all_nbest_json, indent=4) + "\n")
+ if version_2_with_negative:
+ logger.info(f"Saving null_odds to {null_odds_file}.")
+ with open(null_odds_file, "w") as writer:
+ writer.write(json.dumps(scores_diff_json, indent=4) + "\n")
+
+ return all_predictions, scores_diff_json
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/speech-recognition/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/speech-recognition/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..943c98761aa660c8d03e8f3d8fdd462ff612a8db
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/speech-recognition/README.md
@@ -0,0 +1,68 @@
+
+
+# Automatic Speech Recognition - Flax Examples
+
+## Sequence to Sequence
+
+The script [`run_flax_speech_recognition_seq2seq.py`](https://github.com/huggingface/transformers/blob/main/examples/flax/speech-recognition/run_flax_speech_recognition_seq2seq.py)
+can be used to fine-tune any [Flax Speech Sequence-to-Sequence Model](https://huggingface.co/docs/transformers/main/en/model_doc/auto#transformers.FlaxAutoModelForSpeechSeq2Seq)
+for automatic speech recognition on one of the [official speech recognition datasets](https://huggingface.co/datasets?task_ids=task_ids:automatic-speech-recognition)
+or a custom dataset. This includes the Whisper model from OpenAI, or a warm-started Speech-Encoder-Decoder Model,
+an example for which is included below.
+
+### Whisper Model
+
+We can load all components of the Whisper model directly from the pretrained checkpoint, including the pretrained model
+weights, feature extractor and tokenizer. We simply have to specify the id of fine-tuning dataset and the necessary
+training hyperparameters.
+
+The following example shows how to fine-tune the [Whisper small](https://huggingface.co/openai/whisper-small) checkpoint
+on the Hindi subset of the [Common Voice 13](https://huggingface.co/datasets/mozilla-foundation/common_voice_13_0) dataset.
+Note that before running this script you must accept the dataset's [terms of use](https://huggingface.co/datasets/mozilla-foundation/common_voice_13_0)
+and register your Hugging Face Hub token on your device by running `huggingface-hub login`.
+
+```bash
+python run_flax_speech_recognition_seq2seq.py \
+ --model_name_or_path="openai/whisper-small" \
+ --dataset_name="mozilla-foundation/common_voice_13_0" \
+ --dataset_config_name="hi" \
+ --language="hindi" \
+ --train_split_name="train+validation" \
+ --eval_split_name="test" \
+ --output_dir="./whisper-small-hi-flax" \
+ --per_device_train_batch_size="16" \
+ --per_device_eval_batch_size="16" \
+ --num_train_epochs="10" \
+ --learning_rate="1e-4" \
+ --warmup_steps="500" \
+ --logging_steps="25" \
+ --generation_max_length="40" \
+ --preprocessing_num_workers="32" \
+ --dataloader_num_workers="32" \
+ --max_duration_in_seconds="30" \
+ --text_column_name="sentence" \
+ --overwrite_output_dir \
+ --do_train \
+ --do_eval \
+ --predict_with_generate \
+ --push_to_hub \
+ --use_auth_token
+```
+
+On a TPU v4-8, training should take approximately 25 minutes, with a final cross-entropy loss of 0.02 and word error
+rate of **34%**. See the checkpoint [sanchit-gandhi/whisper-small-hi-flax](https://huggingface.co/sanchit-gandhi/whisper-small-hi-flax)
+for an example training run.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/speech-recognition/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/speech-recognition/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..b68b236ad76c2b06e7e7e7711d90c5f2914a7bcb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/speech-recognition/requirements.txt
@@ -0,0 +1,8 @@
+datasets[audio]>=2.14.0
+jax>=0.3.6
+jaxlib>=0.3.6
+flax>=0.4.1
+optax>=0.0.8
+torch>=1.9.0
+jiwer
+evaluate
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/speech-recognition/run_flax_speech_recognition_seq2seq.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/speech-recognition/run_flax_speech_recognition_seq2seq.py
new file mode 100644
index 0000000000000000000000000000000000000000..ae106c7264317b154e8fb727ecfc8e88343550ff
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/speech-recognition/run_flax_speech_recognition_seq2seq.py
@@ -0,0 +1,878 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2023 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the Flax library models for sequence to sequence speech recognition.
+"""
+# You can also adapt this script on your own sequence to sequence task. Pointers for this are left as comments.
+
+import logging
+import os
+import sys
+import time
+from dataclasses import field
+from functools import partial
+from pathlib import Path
+from typing import Any, Callable, Dict, List, Optional, Union
+
+import datasets
+import evaluate
+import flax
+import jax
+import jax.numpy as jnp
+import numpy as np
+import optax
+from datasets import DatasetDict, load_dataset
+from flax import jax_utils, traverse_util
+from flax.jax_utils import pad_shard_unpad, unreplicate
+from flax.training import train_state
+from flax.training.common_utils import get_metrics, onehot, shard, shard_prng_key
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from tqdm import tqdm
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoFeatureExtractor,
+ AutoProcessor,
+ AutoTokenizer,
+ FlaxAutoModelForSpeechSeq2Seq,
+ HfArgumentParser,
+ Seq2SeqTrainingArguments,
+ is_tensorboard_available,
+)
+from transformers.file_utils import get_full_repo_name
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risk.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=2.14.0", "To fix: pip install -r examples/flax/speech-recognition/requirements.txt")
+
+logger = logging.getLogger(__name__)
+
+
+@flax.struct.dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ feature_extractor_name: Optional[str] = field(
+ default=None, metadata={"help": "feature extractor name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where to store the pretrained models downloaded from huggingface.co"},
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ use_auth_token: bool = field(
+ default=False,
+ metadata={
+ "help": "Will use the token generated when running `transformers-cli login` (necessary to use this script "
+ "with private models)."
+ },
+ )
+ dtype: Optional[str] = field(
+ default="float32",
+ metadata={
+ "help": (
+ "Floating-point format in which the model weights should be initialized and trained. Choose one of"
+ " `[float32, float16, bfloat16]`."
+ )
+ },
+ )
+ num_beams: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Number of beams to use for evaluation. This argument will be passed to `model.generate`, "
+ "which is used during evaluation."
+ )
+ },
+ )
+
+
+@flax.struct.dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: str = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ text_column: Optional[str] = field(
+ default=None,
+ metadata={"help": "The name of the column in the datasets containing the full texts (for summarization)."},
+ )
+ dataset_cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Path to cache directory for saving and loading datasets"}
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ },
+ )
+ audio_column_name: str = field(
+ default="audio",
+ metadata={"help": "The name of the dataset column containing the audio data. Defaults to 'audio'"},
+ )
+ text_column_name: str = field(
+ default="text",
+ metadata={"help": "The name of the dataset column containing the text data. Defaults to 'text'"},
+ )
+ max_duration_in_seconds: float = field(
+ default=20.0,
+ metadata={"help": "Filter audio files that are longer than `max_duration_in_seconds` seconds"},
+ )
+ min_duration_in_seconds: float = field(
+ default=0.0,
+ metadata={"help": "Filter audio files that are shorter than `min_duration_in_seconds` seconds"},
+ )
+ max_label_length: float = field(
+ default=128,
+ metadata={"help": "Truncate transcriptions that are longer `max_eval_length` tokens."},
+ )
+ pad_input_to_multiple_of: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": "If set will pad the input sequence to a multiple of the provided value. "
+ "This is important to avoid triggering recompilations on TPU. If unspecified, will default to padding the inputs to max length."
+ },
+ )
+ pad_target_to_multiple_of: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": "If set will pad the target sequence to a multiple of the provided value. "
+ "This is important to avoid triggering recompilations on TPU. If unspecified, will default to padding the targets to max length."
+ },
+ )
+ preprocessing_only: bool = field(
+ default=False,
+ metadata={
+ "help": "Whether to only do data preprocessing and skip training. "
+ "This is especially useful when data preprocessing errors out in distributed training due to timeout. "
+ "In this case, one should run the preprocessing in a non-distributed setup with `preprocessing_only=True` "
+ "so that the cached datasets can consequently be loaded in distributed training"
+ },
+ )
+ train_split_name: str = field(
+ default="train",
+ metadata={
+ "help": "The name of the training data set split to use (via the datasets library). Defaults to 'train'"
+ },
+ )
+ eval_split_name: str = field(
+ default="validation",
+ metadata={
+ "help": "The name of the evaluation data set split to use (via the datasets library). Defaults to 'validation'"
+ },
+ )
+ do_lower_case: bool = field(
+ default=True,
+ metadata={"help": "Whether the target text should be lower cased."},
+ )
+ language: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "Language for multilingual fine-tuning. This argument should be set for multilingual fine-tuning "
+ "only. For English speech recognition, it should be set to `None`."
+ )
+ },
+ )
+ task: str = field(
+ default="transcribe",
+ metadata={"help": "Task, either `transcribe` for speech recognition or `translate` for speech translation."},
+ )
+
+
+def shift_tokens_right(label_ids: np.array, decoder_start_token_id: int) -> np.ndarray:
+ """
+ Shift label ids one token to the right.
+ """
+ shifted_label_ids = np.zeros_like(label_ids)
+ shifted_label_ids[:, 1:] = label_ids[:, :-1]
+ shifted_label_ids[:, 0] = decoder_start_token_id
+
+ return shifted_label_ids
+
+
+@flax.struct.dataclass
+class FlaxDataCollatorSpeechSeq2SeqWithPadding:
+ """
+ Data collator that will dynamically pad the inputs received.
+ Args:
+ processor ([`Wav2Vec2Processor`])
+ The processor used for proccessing the data.
+ decoder_start_token_id (:obj: `int`)
+ The begin-of-sentence of the decoder.
+ input_padding (:obj:`bool`, :obj:`str` or :class:`~transformers.tokenization_utils_base.PaddingStrategy`, `optional`, defaults to :obj:`True`):
+ Select a strategy to pad the returned input sequences (according to the model's padding side and padding index)
+ among:
+ * :obj:`True` or :obj:`'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
+ sequence if provided).
+ * :obj:`'max_length'`: Pad to a maximum length specified with the argument :obj:`max_length` or to the
+ maximum acceptable input length for the model if that argument is not provided.
+ * :obj:`False` or :obj:`'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of
+ different lengths).
+ target_padding (:obj:`bool`, :obj:`str` or :class:`~transformers.tokenization_utils_base.PaddingStrategy`, `optional`, defaults to :obj:`True`):
+ Select a strategy to pad the returned target sequences (according to the model's padding side and padding index).
+ See above for details.
+ max_input_length (:obj:`float`, `optional`):
+ Maximum length of the ``input_values`` of the returned list and optionally padding length (see above).
+ max_target_length (:obj:`int`, `optional`):
+ Maximum length of the ``labels`` of the returned list and optionally padding length (see above).
+ pad_input_to_multiple_of (:obj:`int`, `optional`):
+ If set will pad the input sequence to a multiple of the provided value.
+ This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability >=
+ 7.5 (Volta).
+ pad_target_to_multiple_of (:obj:`int`, `optional`):
+ If set will pad the target sequence to a multiple of the provided value.
+ This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability >=
+ 7.5 (Volta).
+ """
+
+ processor: Any
+ decoder_start_token_id: int
+ input_padding: Union[bool, str] = "longest"
+ target_padding: Union[bool, str] = "max_length"
+ max_input_length: Optional[float] = None
+ max_target_length: Optional[int] = None
+ pad_input_to_multiple_of: Optional[int] = None
+ pad_target_to_multiple_of: Optional[int] = None
+
+ def __call__(self, features: List[Dict[str, Union[List[int], np.ndarray]]]) -> Dict[str, np.ndarray]:
+ # split inputs and labels since they have to be of different lengths and need
+ # different padding methods
+ model_input_name = self.processor.model_input_names[0]
+
+ # dataloader returns a list of features which we convert to a dict
+ input_features = {model_input_name: [feature[model_input_name] for feature in features]}
+ label_features = {"input_ids": [feature["labels"] for feature in features]}
+
+ # reformat list to dict and set to pytorch format
+ batch = self.processor.feature_extractor.pad(
+ input_features,
+ max_length=self.max_input_length,
+ padding=self.input_padding,
+ pad_to_multiple_of=self.pad_input_to_multiple_of,
+ return_tensors="np",
+ )
+
+ labels_batch = self.processor.tokenizer.pad(
+ label_features,
+ max_length=self.max_target_length,
+ padding=self.target_padding,
+ pad_to_multiple_of=self.pad_target_to_multiple_of,
+ return_tensors="np",
+ )
+
+ # if bos token is appended in previous tokenization step,
+ # cut bos token here as it's append later anyways
+ labels = labels_batch["input_ids"]
+ if (labels[:, 0] == self.decoder_start_token_id).all().item():
+ labels = labels[:, 1:]
+ labels_batch.attention_mask = labels_batch.attention_mask[:, 1:]
+
+ decoder_input_ids = shift_tokens_right(labels, self.decoder_start_token_id)
+
+ # replace padding with -100 to ignore correctly when computing the loss
+ labels = np.ma.array(labels, mask=np.not_equal(labels_batch.attention_mask, 1))
+ labels = labels.filled(fill_value=-100)
+
+ batch["labels"] = labels
+ batch["decoder_input_ids"] = decoder_input_ids
+
+ return batch
+
+
+class TrainState(train_state.TrainState):
+ dropout_rng: jnp.ndarray
+
+ def replicate(self):
+ return jax_utils.replicate(self).replace(dropout_rng=shard_prng_key(self.dropout_rng))
+
+
+def write_metric(summary_writer, train_metrics, eval_metrics, train_time, step):
+ summary_writer.scalar("train_time", train_time, step)
+
+ train_metrics = get_metrics(train_metrics)
+ for key, vals in train_metrics.items():
+ tag = f"train_{key}"
+ for i, val in enumerate(vals):
+ summary_writer.scalar(tag, val, step - len(vals) + i + 1)
+
+ for metric_name, value in eval_metrics.items():
+ summary_writer.scalar(f"eval_{metric_name}", value, step)
+
+
+def create_learning_rate_fn(
+ num_train_steps: int, num_warmup_steps: int, learning_rate: float
+) -> Callable[[int], jnp.ndarray]:
+ """Returns a linear warmup, linear_decay learning rate function."""
+ warmup_fn = optax.linear_schedule(init_value=0.0, end_value=learning_rate, transition_steps=num_warmup_steps)
+ decay_fn = optax.linear_schedule(
+ init_value=learning_rate, end_value=0, transition_steps=num_train_steps - num_warmup_steps
+ )
+ schedule_fn = optax.join_schedules(schedules=[warmup_fn, decay_fn], boundaries=[num_warmup_steps])
+ return schedule_fn
+
+
+def main():
+ # 1. Parse input arguments
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, Seq2SeqTrainingArguments))
+
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your JAX/Flax versions.
+ send_example_telemetry("run_speech_recognition_seq2seq", model_args, data_args, framework="flax")
+
+ # 2. Setup logging
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+ # Set the verbosity to info of the Transformers logger.
+ # We only want one process per machine to log things on the screen.
+ logger.setLevel(logging.INFO if jax.process_index() == 0 else logging.ERROR)
+ if jax.process_index() == 0:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ logger.info("Training/evaluation parameters %s", training_args)
+
+ # Check the output dir is valid
+ if (
+ os.path.exists(training_args.output_dir)
+ and os.listdir(training_args.output_dir)
+ and training_args.do_train
+ and not training_args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use `--overwrite_output_dir` to overcome."
+ )
+
+ # Handle the repository creation
+ if training_args.push_to_hub:
+ if training_args.hub_model_id is None:
+ repo_name = get_full_repo_name(
+ Path(training_args.output_dir).absolute().name, token=training_args.hub_token
+ )
+ else:
+ repo_name = training_args.hub_model_id
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=training_args.hub_token).repo_id
+
+ # 3. Load dataset
+ raw_datasets = DatasetDict()
+
+ if training_args.do_train:
+ raw_datasets["train"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=data_args.train_split_name,
+ cache_dir=data_args.dataset_cache_dir,
+ num_proc=data_args.preprocessing_num_workers,
+ token=True if model_args.use_auth_token else None,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+
+ if training_args.do_eval:
+ raw_datasets["eval"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=data_args.eval_split_name,
+ cache_dir=data_args.dataset_cache_dir,
+ num_proc=data_args.preprocessing_num_workers,
+ token=True if model_args.use_auth_token else None,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+
+ if not training_args.do_train and not training_args.do_eval:
+ raise ValueError(
+ "Cannot not train and not do evaluation. At least one of training or evaluation has to be performed."
+ )
+
+ if data_args.audio_column_name not in next(iter(raw_datasets.values())).column_names:
+ raise ValueError(
+ f"--audio_column_name '{data_args.audio_column_name}' not found in dataset '{data_args.dataset_name}'. "
+ "Make sure to set `--audio_column_name` to the correct audio column - one of "
+ f"{', '.join(next(iter(raw_datasets.values())).column_names)}."
+ )
+
+ if data_args.text_column_name not in next(iter(raw_datasets.values())).column_names:
+ raise ValueError(
+ f"--text_column_name {data_args.text_column_name} not found in dataset '{data_args.dataset_name}'. "
+ "Make sure to set `--text_column_name` to the correct text column - one of "
+ f"{', '.join(next(iter(raw_datasets.values())).column_names)}."
+ )
+
+ # 5. Load pretrained model, tokenizer, and feature extractor
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=True if model_args.use_auth_token else None,
+ )
+ feature_extractor = AutoFeatureExtractor.from_pretrained(
+ model_args.feature_extractor_name if model_args.feature_extractor_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=True if model_args.use_auth_token else None,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ revision=model_args.model_revision,
+ token=True if model_args.use_auth_token else None,
+ )
+
+ model = FlaxAutoModelForSpeechSeq2Seq.from_pretrained(
+ model_args.model_name_or_path,
+ config=config,
+ dtype=getattr(jnp, model_args.dtype),
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=True if model_args.use_auth_token else None,
+ )
+
+ if model.config.decoder_start_token_id is None:
+ raise ValueError("Make sure that `config.decoder_start_token_id` is correctly defined")
+
+ # 6. Resample speech dataset: `datasets` takes care of automatically loading and resampling the audio,
+ # so we just need to set the correct target sampling rate.
+ raw_datasets = raw_datasets.cast_column(
+ data_args.audio_column_name, datasets.features.Audio(sampling_rate=feature_extractor.sampling_rate)
+ )
+
+ # 7. Preprocessing the datasets.
+ # We need to read the audio files as arrays and tokenize the targets.
+ max_input_length = int(data_args.max_duration_in_seconds * feature_extractor.sampling_rate)
+ min_input_length = int(data_args.min_duration_in_seconds * feature_extractor.sampling_rate)
+ max_label_length = (
+ data_args.max_label_length if data_args.max_label_length is not None else model.config.max_length
+ )
+ pad_input_to_multiple_of = data_args.pad_input_to_multiple_of
+ pad_target_to_multiple_of = data_args.pad_target_to_multiple_of
+ audio_column_name = data_args.audio_column_name
+ num_workers = data_args.preprocessing_num_workers
+ text_column_name = data_args.text_column_name
+ model_input_name = feature_extractor.model_input_names[0]
+ do_lower_case = data_args.do_lower_case
+
+ if training_args.do_train and data_args.max_train_samples is not None:
+ raw_datasets["train"] = raw_datasets["train"].select(range(data_args.max_train_samples))
+
+ if training_args.do_eval and data_args.max_eval_samples is not None:
+ raw_datasets["eval"] = raw_datasets["eval"].select(range(data_args.max_eval_samples))
+
+ if data_args.language is not None:
+ # We only need to set the task id when the language is specified (i.e. in a multilingual setting)
+ tokenizer.set_prefix_tokens(language=data_args.language, task=data_args.task)
+
+ def prepare_dataset(batch):
+ # process audio
+ sample = batch[audio_column_name]
+ inputs = feature_extractor(sample["array"], sampling_rate=sample["sampling_rate"])
+ # process audio length
+ batch[model_input_name] = inputs.get(model_input_name)[0]
+ batch["input_length"] = len(sample["array"])
+
+ # process targets
+ input_str = batch[text_column_name].lower() if do_lower_case else batch[text_column_name]
+ batch["labels"] = tokenizer(input_str).input_ids
+ return batch
+
+ vectorized_datasets = raw_datasets.map(
+ prepare_dataset,
+ remove_columns=next(iter(raw_datasets.values())).column_names,
+ num_proc=num_workers,
+ desc="preprocess train and eval dataset",
+ )
+
+ # filter training data with inputs longer than max_input_length
+ def is_audio_in_length_range(length):
+ return min_input_length < length < max_input_length
+
+ vectorized_datasets = vectorized_datasets.filter(
+ is_audio_in_length_range,
+ num_proc=num_workers,
+ input_columns=["input_length"],
+ )
+
+ # for large datasets it is advised to run the preprocessing on a
+ # single machine first with `args.preprocessing_only` since there will mostly likely
+ # be a timeout when running the script in distributed mode.
+ # In a second step `args.preprocessing_only` can then be set to `False` to load the
+ # cached dataset
+ if data_args.preprocessing_only:
+ cache = {k: v.cache_files for k, v in vectorized_datasets.items()}
+ logger.info(f"Data preprocessing finished. Files cached at {cache}.")
+ return
+
+ # 8. Load Metric
+ metric = evaluate.load("wer", cache_dir=model_args.cache_dir)
+
+ def compute_metrics(preds, labels):
+ # replace padded labels by the padding token
+ for idx in range(len(labels)):
+ labels[idx][labels[idx] == -100] = tokenizer.pad_token_id
+
+ pred_str = tokenizer.batch_decode(preds, skip_special_tokens=True)
+ # we do not want to group tokens when computing the metrics
+ label_str = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+ wer = metric.compute(predictions=pred_str, references=label_str)
+ return {"wer": wer}
+
+ # 9. Save feature extractor, tokenizer and config
+ feature_extractor.save_pretrained(training_args.output_dir)
+ tokenizer.save_pretrained(training_args.output_dir)
+ config.save_pretrained(training_args.output_dir)
+
+ processor = AutoProcessor.from_pretrained(training_args.output_dir)
+
+ data_collator = FlaxDataCollatorSpeechSeq2SeqWithPadding(
+ processor=processor,
+ decoder_start_token_id=model.config.decoder_start_token_id,
+ input_padding="longest",
+ target_padding="longest",
+ max_target_length=max_label_length,
+ pad_input_to_multiple_of=pad_input_to_multiple_of,
+ pad_target_to_multiple_of=pad_target_to_multiple_of if pad_target_to_multiple_of else max_label_length,
+ )
+
+ # Enable tensorboard only on the master node
+ has_tensorboard = is_tensorboard_available()
+ if has_tensorboard and jax.process_index() == 0:
+ try:
+ from flax.metrics.tensorboard import SummaryWriter
+
+ summary_writer = SummaryWriter(log_dir=Path(training_args.output_dir))
+ except ImportError as ie:
+ has_tensorboard = False
+ logger.warning(
+ f"Unable to display metrics through TensorBoard because some package are not installed: {ie}"
+ )
+ else:
+ logger.warning(
+ "Unable to display metrics through TensorBoard because the package is not installed: "
+ "Please run pip install tensorboard to enable."
+ )
+
+ # Initialize our training
+ rng = jax.random.PRNGKey(training_args.seed)
+ rng, dropout_rng = jax.random.split(rng)
+
+ # Store some constant
+ num_epochs = int(training_args.num_train_epochs)
+ train_batch_size = int(training_args.per_device_train_batch_size) * jax.device_count()
+ per_device_eval_batch_size = int(training_args.per_device_eval_batch_size)
+ eval_batch_size = per_device_eval_batch_size * jax.device_count()
+ steps_per_epoch = len(vectorized_datasets["train"]) // train_batch_size
+ total_train_steps = steps_per_epoch * num_epochs
+
+ # Create learning rate schedule
+ linear_decay_lr_schedule_fn = create_learning_rate_fn(
+ total_train_steps,
+ training_args.warmup_steps,
+ training_args.learning_rate,
+ )
+
+ # We use Optax's "masking" functionality to not apply weight decay
+ # to bias and LayerNorm scale parameters. decay_mask_fn returns a
+ # mask boolean with the same structure as the parameters.
+ # The mask is True for parameters that should be decayed.
+ def decay_mask_fn(params):
+ flat_params = traverse_util.flatten_dict(params)
+ # find out all LayerNorm parameters
+ layer_norm_candidates = ["layer_norm", "self_attn_layer_norm", "final_layer_norm", "encoder_attn_layer_norm"]
+ layer_norm_named_params = {
+ layer[-2:]
+ for layer_norm_name in layer_norm_candidates
+ for layer in flat_params.keys()
+ if layer_norm_name in "".join(layer).lower()
+ }
+ flat_mask = {path: (path[-1] != "bias" and path[-2:] not in layer_norm_named_params) for path in flat_params}
+ return traverse_util.unflatten_dict(flat_mask)
+
+ # create adam optimizer
+ adamw = optax.adamw(
+ learning_rate=linear_decay_lr_schedule_fn,
+ b1=training_args.adam_beta1,
+ b2=training_args.adam_beta2,
+ eps=training_args.adam_epsilon,
+ weight_decay=training_args.weight_decay,
+ mask=decay_mask_fn,
+ )
+
+ # Setup train state
+ state = TrainState.create(apply_fn=model.__call__, params=model.params, tx=adamw, dropout_rng=dropout_rng)
+
+ # label smoothed cross entropy
+ def loss_fn(logits, labels, label_smoothing_factor=0.0):
+ """
+ The label smoothing implementation is adapted from Flax's official example:
+ https://github.com/google/flax/blob/87a211135c6a377c8f29048a1cac3840e38b9da4/examples/wmt/train.py#L104
+ """
+ vocab_size = logits.shape[-1]
+ confidence = 1.0 - label_smoothing_factor
+ low_confidence = (1.0 - confidence) / (vocab_size - 1)
+ normalizing_constant = -(
+ confidence * jnp.log(confidence) + (vocab_size - 1) * low_confidence * jnp.log(low_confidence + 1e-20)
+ )
+ soft_labels = onehot(labels, vocab_size, on_value=confidence, off_value=low_confidence)
+
+ loss = optax.softmax_cross_entropy(logits, soft_labels)
+ loss = loss - normalizing_constant
+
+ # ignore padded tokens from loss, i.e. where labels are not set to -100
+ padding_mask = labels >= 0
+ loss = loss * padding_mask
+ loss = loss.sum()
+ num_labels = padding_mask.sum()
+ return loss, num_labels
+
+ # Define gradient update step fn
+ def train_step(state, batch, label_smoothing_factor=0.0):
+ dropout_rng, new_dropout_rng = jax.random.split(state.dropout_rng)
+
+ def compute_loss(params):
+ labels = batch.pop("labels")
+ logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
+ loss, num_labels = loss_fn(logits, labels, label_smoothing_factor)
+ return loss, num_labels
+
+ grad_fn = jax.value_and_grad(compute_loss, has_aux=True)
+ (loss, num_labels), grad = grad_fn(state.params)
+ num_labels = jax.lax.psum(num_labels, "batch")
+
+ # true loss = total loss / total samples
+ loss = jax.lax.psum(loss, "batch")
+ loss = jax.tree_util.tree_map(lambda x: x / num_labels, loss)
+
+ # true grad = total grad / total samples
+ grad = jax.lax.psum(grad, "batch")
+ grad = jax.tree_util.tree_map(lambda x: x / num_labels, grad)
+ new_state = state.apply_gradients(grads=grad, dropout_rng=new_dropout_rng)
+
+ metrics = {"loss": loss, "learning_rate": linear_decay_lr_schedule_fn(state.step)}
+ return new_state, metrics
+
+ # Define eval fn
+ def eval_step(params, batch, label_smoothing_factor=0.0):
+ labels = batch.pop("labels")
+ logits = model(**batch, params=params, train=False)[0]
+
+ loss, num_labels = loss_fn(logits, labels, label_smoothing_factor)
+ num_labels = jax.lax.psum(num_labels, "batch")
+
+ # true loss = total loss / total samples
+ loss = jax.lax.psum(loss, "batch")
+ loss = jax.tree_util.tree_map(lambda x: x / num_labels, loss)
+
+ metrics = {"loss": loss}
+ return metrics
+
+ # Define generation function
+ num_beams = model_args.num_beams if model_args.num_beams is not None else model.config.num_beams
+ gen_kwargs = {"max_length": max_label_length, "num_beams": num_beams}
+
+ def generate_step(params, batch):
+ model.params = params
+ output_ids = model.generate(batch[model_input_name], attention_mask=batch.get("attention_mask"), **gen_kwargs)
+ return output_ids.sequences
+
+ # Create parallel version of the train and eval step
+ p_train_step = jax.pmap(
+ partial(train_step, label_smoothing_factor=training_args.label_smoothing_factor), "batch", donate_argnums=(0,)
+ )
+ p_eval_step = jax.pmap(partial(eval_step, label_smoothing_factor=training_args.label_smoothing_factor), "batch")
+ p_generate_step = jax.pmap(generate_step, "batch")
+
+ # Replicate the train state on each device
+ state = state.replicate()
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(vectorized_datasets['train'])}")
+ logger.info(f" Num Epochs = {num_epochs}")
+ logger.info(f" Instantaneous batch size per device = {training_args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel & distributed) = {train_batch_size}")
+ logger.info(f" Total optimization steps = {total_train_steps}")
+
+ train_time = 0
+ epochs = tqdm(range(num_epochs), desc=f"Epoch ... (1/{num_epochs})", position=0)
+ for epoch in epochs:
+ # ======================== Training ================================
+ train_start = time.time()
+
+ train_metrics = []
+
+ # Generate an epoch by shuffling sampling indices from the train dataset and create a data loader
+ vectorized_datasets["train"] = vectorized_datasets["train"].shuffle(training_args.seed)
+ train_loader = DataLoader(
+ vectorized_datasets["train"],
+ batch_size=train_batch_size,
+ drop_last=True,
+ collate_fn=data_collator,
+ num_workers=training_args.dataloader_num_workers,
+ )
+ # train
+ for batch in tqdm(train_loader, desc="Training...", position=1, leave=False):
+ batch = shard(batch.data)
+ state, train_metric = p_train_step(state, batch)
+ train_metrics.append(train_metric)
+
+ train_time += time.time() - train_start
+
+ train_metric = unreplicate(train_metric)
+
+ epochs.write(
+ f"Epoch... ({epoch + 1}/{num_epochs} | Loss: {train_metric['loss']}, Learning Rate:"
+ f" {train_metric['learning_rate']})"
+ )
+
+ # ======================== Evaluating ==============================
+ eval_metrics = []
+ eval_preds = []
+ eval_labels = []
+
+ eval_loader = DataLoader(
+ vectorized_datasets["eval"],
+ batch_size=eval_batch_size,
+ drop_last=False,
+ collate_fn=data_collator,
+ num_workers=training_args.dataloader_num_workers,
+ )
+ for batch in tqdm(eval_loader, desc="Evaluating...", position=2, leave=False):
+ # Model forward
+ labels = batch["labels"]
+
+ metrics = pad_shard_unpad(p_eval_step, static_return=True)(
+ state.params, batch.data, min_device_batch=per_device_eval_batch_size
+ )
+ eval_metrics.append(metrics)
+
+ # generation
+ if training_args.predict_with_generate:
+ generated_ids = pad_shard_unpad(p_generate_step)(state.params, batch.data)
+ eval_preds.extend(jax.device_get(generated_ids.reshape(-1, gen_kwargs["max_length"])))
+ eval_labels.extend(labels)
+
+ # normalize eval metrics
+ eval_metrics = get_metrics(eval_metrics)
+ eval_metrics = jax.tree_util.tree_map(jnp.mean, eval_metrics)
+
+ # compute WER metric
+ wer_desc = ""
+ if training_args.predict_with_generate:
+ wer_metric = compute_metrics(eval_preds, eval_labels)
+ eval_metrics.update(wer_metric)
+ wer_desc = " ".join([f"Eval {key}: {value} |" for key, value in wer_metric.items()])
+
+ # Print metrics and update progress bar
+ desc = f"Epoch... ({epoch + 1}/{num_epochs} | Eval Loss: {eval_metrics['loss']} | {wer_desc})"
+ epochs.write(desc)
+ epochs.desc = desc
+
+ # Save metrics
+ if has_tensorboard and jax.process_index() == 0:
+ cur_step = epoch * (len(vectorized_datasets["train"]) // train_batch_size)
+ write_metric(summary_writer, train_metrics, eval_metrics, train_time, cur_step)
+
+ # save checkpoint after each epoch and push checkpoint to the hub
+ if jax.process_index() == 0:
+ params = jax.device_get(jax.tree_util.tree_map(lambda x: x[0], state.params))
+ model.save_pretrained(training_args.output_dir, params=params)
+ tokenizer.save_pretrained(training_args.output_dir)
+ if training_args.push_to_hub:
+ api.upload_folder(
+ commit_message=f"Saving weights and logs of epoch {epoch}",
+ folder_path=training_args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=training_args.hub_token,
+ )
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/summarization/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/summarization/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..2eb21f49b65fe282f0e7768554555a94d2962ed2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/summarization/README.md
@@ -0,0 +1,35 @@
+# Summarization (Seq2Seq model) training examples
+
+The following example showcases how to finetune a sequence-to-sequence model for summarization
+using the JAX/Flax backend.
+
+JAX/Flax allows you to trace pure functions and compile them into efficient, fused accelerator code on both GPU and TPU.
+Models written in JAX/Flax are **immutable** and updated in a purely functional
+way which enables simple and efficient model parallelism.
+
+`run_summarization_flax.py` is a lightweight example of how to download and preprocess a dataset from the 🤗 Datasets library or use your own files (jsonlines or csv), then fine-tune one of the architectures above on it.
+
+For custom datasets in `jsonlines` format please see: https://huggingface.co/docs/datasets/loading_datasets#json-files and you also will find examples of these below.
+
+### Train the model
+Next we can run the example script to train the model:
+
+```bash
+python run_summarization_flax.py \
+ --output_dir ./bart-base-xsum \
+ --model_name_or_path facebook/bart-base \
+ --tokenizer_name facebook/bart-base \
+ --dataset_name="xsum" \
+ --do_train --do_eval --do_predict --predict_with_generate \
+ --num_train_epochs 6 \
+ --learning_rate 5e-5 --warmup_steps 0 \
+ --per_device_train_batch_size 64 \
+ --per_device_eval_batch_size 64 \
+ --overwrite_output_dir \
+ --max_source_length 512 --max_target_length 64 \
+ --push_to_hub
+```
+
+This should finish in 37min, with validation loss and ROUGE2 score of 1.7785 and 17.01 respectively after 6 epochs. training statistics can be accessed on [tfhub.dev](https://tensorboard.dev/experiment/OcPfOIgXRMSJqYB4RdK2tA/#scalars).
+
+> Note that here we used default `generate` arguments, using arguments specific for `xsum` dataset should give better ROUGE scores.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/summarization/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/summarization/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..58c7c26af78a065713b0413428a4adeefa365aa4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/summarization/requirements.txt
@@ -0,0 +1,6 @@
+datasets >= 1.1.3
+jax>=0.2.8
+jaxlib>=0.1.59
+flax>=0.3.5
+optax>=0.0.8
+evaluate>=0.2.0
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/summarization/run_summarization_flax.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/summarization/run_summarization_flax.py
new file mode 100644
index 0000000000000000000000000000000000000000..36407df3b41d35e251acbdbceaa06c91471a8297
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/summarization/run_summarization_flax.py
@@ -0,0 +1,1021 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for summarization.
+"""
+# You can also adapt this script on your own sequence to sequence task. Pointers for this are left as comments.
+
+import json
+import logging
+import math
+import os
+import sys
+import time
+from dataclasses import asdict, dataclass, field
+from enum import Enum
+from functools import partial
+from pathlib import Path
+from typing import Callable, Optional
+
+import datasets
+import evaluate
+import jax
+import jax.numpy as jnp
+import nltk # Here to have a nice missing dependency error message early on
+import numpy as np
+import optax
+from datasets import Dataset, load_dataset
+from filelock import FileLock
+from flax import jax_utils, traverse_util
+from flax.jax_utils import pad_shard_unpad, unreplicate
+from flax.training import train_state
+from flax.training.common_utils import get_metrics, onehot, shard, shard_prng_key
+from huggingface_hub import HfApi
+from tqdm import tqdm
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ FLAX_MODEL_FOR_SEQ_TO_SEQ_CAUSAL_LM_MAPPING,
+ AutoConfig,
+ AutoTokenizer,
+ FlaxAutoModelForSeq2SeqLM,
+ HfArgumentParser,
+ is_tensorboard_available,
+)
+from transformers.utils import is_offline_mode, send_example_telemetry
+
+
+logger = logging.getLogger(__name__)
+
+try:
+ nltk.data.find("tokenizers/punkt")
+except (LookupError, OSError):
+ if is_offline_mode():
+ raise LookupError(
+ "Offline mode: run this script without TRANSFORMERS_OFFLINE first to download nltk data files"
+ )
+ with FileLock(".lock") as lock:
+ nltk.download("punkt", quiet=True)
+
+
+MODEL_CONFIG_CLASSES = list(FLAX_MODEL_FOR_SEQ_TO_SEQ_CAUSAL_LM_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+@dataclass
+class TrainingArguments:
+ output_dir: str = field(
+ metadata={"help": "The output directory where the model predictions and checkpoints will be written."},
+ )
+ overwrite_output_dir: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Overwrite the content of the output directory. "
+ "Use this to continue training if output_dir points to a checkpoint directory."
+ )
+ },
+ )
+ do_train: bool = field(default=False, metadata={"help": "Whether to run training."})
+ do_eval: bool = field(default=False, metadata={"help": "Whether to run eval on the dev set."})
+ do_predict: bool = field(default=False, metadata={"help": "Whether to run predictions on the test set."})
+ per_device_train_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for training."}
+ )
+ per_device_eval_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for evaluation."}
+ )
+ learning_rate: float = field(default=5e-5, metadata={"help": "The initial learning rate for AdamW."})
+ weight_decay: float = field(default=0.0, metadata={"help": "Weight decay for AdamW if we apply some."})
+ adam_beta1: float = field(default=0.9, metadata={"help": "Beta1 for AdamW optimizer"})
+ adam_beta2: float = field(default=0.999, metadata={"help": "Beta2 for AdamW optimizer"})
+ adam_epsilon: float = field(default=1e-8, metadata={"help": "Epsilon for AdamW optimizer."})
+ label_smoothing_factor: float = field(
+ default=0.0, metadata={"help": "The label smoothing epsilon to apply (zero means no label smoothing)."}
+ )
+ adafactor: bool = field(default=False, metadata={"help": "Whether or not to replace AdamW by Adafactor."})
+ num_train_epochs: float = field(default=3.0, metadata={"help": "Total number of training epochs to perform."})
+ warmup_steps: int = field(default=0, metadata={"help": "Linear warmup over warmup_steps."})
+ logging_steps: int = field(default=500, metadata={"help": "Log every X updates steps."})
+ save_steps: int = field(default=500, metadata={"help": "Save checkpoint every X updates steps."})
+ eval_steps: int = field(default=None, metadata={"help": "Run an evaluation every X steps."})
+ seed: int = field(default=42, metadata={"help": "Random seed that will be set at the beginning of training."})
+ push_to_hub: bool = field(
+ default=False, metadata={"help": "Whether or not to upload the trained model to the model hub after training."}
+ )
+ hub_model_id: str = field(
+ default=None, metadata={"help": "The name of the repository to keep in sync with the local `output_dir`."}
+ )
+ hub_token: str = field(default=None, metadata={"help": "The token to use to push to the Model Hub."})
+ gradient_checkpointing: bool = field(
+ default=False,
+ metadata={
+ "help": "If True, use gradient checkpointing to save memory at the expense of slower backward pass."
+ },
+ )
+
+ def __post_init__(self):
+ if self.output_dir is not None:
+ self.output_dir = os.path.expanduser(self.output_dir)
+
+ def to_dict(self):
+ """
+ Serializes this instance while replace `Enum` by their values (for JSON serialization support). It obfuscates
+ the token values by removing their value.
+ """
+ d = asdict(self)
+ for k, v in d.items():
+ if isinstance(v, Enum):
+ d[k] = v.value
+ if isinstance(v, list) and len(v) > 0 and isinstance(v[0], Enum):
+ d[k] = [x.value for x in v]
+ if k.endswith("_token"):
+ d[k] = f"<{k.upper()}>"
+ return d
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ model_name_or_path: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
+ )
+ },
+ )
+ model_type: Optional[str] = field(
+ default=None,
+ metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ dtype: Optional[str] = field(
+ default="float32",
+ metadata={
+ "help": (
+ "Floating-point format in which the model weights should be initialized and trained. Choose one of"
+ " `[float32, float16, bfloat16]`."
+ )
+ },
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ text_column: Optional[str] = field(
+ default=None,
+ metadata={"help": "The name of the column in the datasets containing the full texts (for summarization)."},
+ )
+ summary_column: Optional[str] = field(
+ default=None,
+ metadata={"help": "The name of the column in the datasets containing the summaries (for summarization)."},
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ test_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input predict data file to do prediction on (a text file)."},
+ )
+ max_source_length: Optional[int] = field(
+ default=1024,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ max_target_length: Optional[int] = field(
+ default=128,
+ metadata={
+ "help": (
+ "The maximum total sequence length for target text after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ val_max_target_length: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The maximum total sequence length for validation target text after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded. Will default to `max_target_length`. "
+ "This argument is also used to override the `max_length` param of `model.generate`, which is used "
+ "during evaluation."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_predict_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of prediction examples to this "
+ "value if set."
+ )
+ },
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ source_prefix: Optional[str] = field(
+ default=None, metadata={"help": "A prefix to add before every source text (useful for T5 models)."}
+ )
+ predict_with_generate: bool = field(
+ default=False, metadata={"help": "Whether to use generate to calculate generative metrics (ROUGE, BLEU)."}
+ )
+ num_beams: Optional[int] = field(
+ default=1,
+ metadata={
+ "help": (
+ "Number of beams to use for evaluation. This argument will be passed to `model.generate`, "
+ "which is used during evaluation."
+ )
+ },
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+
+ def __post_init__(self):
+ if (
+ self.dataset_name is None
+ and self.train_file is None
+ and self.validation_file is None
+ and self.test_file is None
+ ):
+ raise ValueError("Need either a dataset name or a training, validation, or test file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+ if self.test_file is not None:
+ extension = self.test_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`test_file` should be a csv or a json file."
+ if self.val_max_target_length is None:
+ self.val_max_target_length = self.max_target_length
+
+
+summarization_name_mapping = {
+ "amazon_reviews_multi": ("review_body", "review_title"),
+ "big_patent": ("description", "abstract"),
+ "cnn_dailymail": ("article", "highlights"),
+ "orange_sum": ("text", "summary"),
+ "pn_summary": ("article", "summary"),
+ "psc": ("extract_text", "summary_text"),
+ "samsum": ("dialogue", "summary"),
+ "thaisum": ("body", "summary"),
+ "xglue": ("news_body", "news_title"),
+ "xsum": ("document", "summary"),
+ "wiki_summary": ("article", "highlights"),
+}
+
+
+class TrainState(train_state.TrainState):
+ dropout_rng: jnp.ndarray
+
+ def replicate(self):
+ return jax_utils.replicate(self).replace(dropout_rng=shard_prng_key(self.dropout_rng))
+
+
+def data_loader(rng: jax.random.PRNGKey, dataset: Dataset, batch_size: int, shuffle: bool = False, drop_last=True):
+ """
+ Returns batches of size `batch_size` from `dataset`. If `drop_last` is set to `False`, the final batch may be incomplete,
+ and range in size from 1 to `batch_size`. Shuffle batches if `shuffle` is `True`.
+ """
+ if shuffle:
+ batch_idx = jax.random.permutation(rng, len(dataset))
+ batch_idx = np.asarray(batch_idx)
+ else:
+ batch_idx = np.arange(len(dataset))
+
+ if drop_last:
+ steps_per_epoch = len(dataset) // batch_size
+ batch_idx = batch_idx[: steps_per_epoch * batch_size] # Skip incomplete batch.
+ batch_idx = batch_idx.reshape((steps_per_epoch, batch_size))
+ else:
+ steps_per_epoch = math.ceil(len(dataset) / batch_size)
+ batch_idx = np.array_split(batch_idx, steps_per_epoch)
+
+ for idx in batch_idx:
+ batch = dataset[idx]
+ batch = {k: np.array(v) for k, v in batch.items()}
+
+ yield batch
+
+
+def write_metric(summary_writer, train_metrics, eval_metrics, train_time, step):
+ summary_writer.scalar("train_time", train_time, step)
+
+ train_metrics = get_metrics(train_metrics)
+ for key, vals in train_metrics.items():
+ tag = f"train_{key}"
+ for i, val in enumerate(vals):
+ summary_writer.scalar(tag, val, step - len(vals) + i + 1)
+
+ for metric_name, value in eval_metrics.items():
+ summary_writer.scalar(f"eval_{metric_name}", value, step)
+
+
+def create_learning_rate_fn(
+ train_ds_size: int, train_batch_size: int, num_train_epochs: int, num_warmup_steps: int, learning_rate: float
+) -> Callable[[int], jnp.ndarray]:
+ """Returns a linear warmup, linear_decay learning rate function."""
+ steps_per_epoch = train_ds_size // train_batch_size
+ num_train_steps = steps_per_epoch * num_train_epochs
+ warmup_fn = optax.linear_schedule(init_value=0.0, end_value=learning_rate, transition_steps=num_warmup_steps)
+ decay_fn = optax.linear_schedule(
+ init_value=learning_rate, end_value=0, transition_steps=num_train_steps - num_warmup_steps
+ )
+ schedule_fn = optax.join_schedules(schedules=[warmup_fn, decay_fn], boundaries=[num_warmup_steps])
+ return schedule_fn
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_summarization", model_args, data_args, framework="flax")
+
+ if (
+ os.path.exists(training_args.output_dir)
+ and os.listdir(training_args.output_dir)
+ and training_args.do_train
+ and not training_args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ # Setup logging, we only want one process per machine to log things on the screen.
+ logger.setLevel(logging.INFO if jax.process_index() == 0 else logging.ERROR)
+ if jax.process_index() == 0:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Handle the repository creation
+ if training_args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = training_args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(training_args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=training_args.hub_token).repo_id
+
+ # Get the datasets: you can either provide your own CSV/JSON training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files this script will use the first column for the full texts and the second column for the
+ # summaries (unless you specify column names for this with the `text_column` and `summary_column` arguments).
+ #
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ dataset = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ keep_in_memory=False,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ if data_args.test_file is not None:
+ data_files["test"] = data_args.test_file
+ extension = data_args.test_file.split(".")[-1]
+ dataset = load_dataset(
+ extension,
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+
+ if model_args.config_name:
+ config = AutoConfig.from_pretrained(
+ model_args.config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ elif model_args.model_name_or_path:
+ config = AutoConfig.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ config = CONFIG_MAPPING[model_args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ if model_args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ elif model_args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if model_args.model_name_or_path:
+ model = FlaxAutoModelForSeq2SeqLM.from_pretrained(
+ model_args.model_name_or_path,
+ config=config,
+ seed=training_args.seed,
+ dtype=getattr(jnp, model_args.dtype),
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ model = FlaxAutoModelForSeq2SeqLM.from_config(
+ config,
+ seed=training_args.seed,
+ dtype=getattr(jnp, model_args.dtype),
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ if training_args.gradient_checkpointing:
+ model.enable_gradient_checkpointing()
+
+ if model.config.decoder_start_token_id is None:
+ raise ValueError("Make sure that `config.decoder_start_token_id` is correctly defined")
+
+ prefix = data_args.source_prefix if data_args.source_prefix is not None else ""
+
+ # Preprocessing the datasets.
+ # We need to tokenize inputs and targets.
+ if training_args.do_train:
+ if "train" not in dataset:
+ raise ValueError("--do_train requires a train dataset")
+ column_names = dataset["train"].column_names
+ elif training_args.do_eval:
+ if "validation" not in dataset:
+ raise ValueError("--do_eval requires a validation dataset")
+ column_names = dataset["validation"].column_names
+ elif training_args.do_predict:
+ if "test" not in dataset:
+ raise ValueError("--do_predict requires a test dataset")
+ column_names = dataset["test"].column_names
+ else:
+ logger.info("There is nothing to do. Please pass `do_train`, `do_eval` and/or `do_predict`.")
+ return
+
+ # Get the column names for input/target.
+ dataset_columns = summarization_name_mapping.get(data_args.dataset_name, None)
+ if data_args.text_column is None:
+ text_column = dataset_columns[0] if dataset_columns is not None else column_names[0]
+ else:
+ text_column = data_args.text_column
+ if text_column not in column_names:
+ raise ValueError(
+ f"--text_column' value '{data_args.text_column}' needs to be one of: {', '.join(column_names)}"
+ )
+ if data_args.summary_column is None:
+ summary_column = dataset_columns[1] if dataset_columns is not None else column_names[1]
+ else:
+ summary_column = data_args.summary_column
+ if summary_column not in column_names:
+ raise ValueError(
+ f"--summary_column' value '{data_args.summary_column}' needs to be one of: {', '.join(column_names)}"
+ )
+
+ # Temporarily set max_target_length for training.
+ max_target_length = data_args.max_target_length
+
+ # In Flax, for seq2seq models we need to pass `decoder_input_ids`
+ # as the Flax models don't accept `labels`, we need to prepare the decoder_input_ids here
+ # for that dynamically import the `shift_tokens_right` function from the model file
+ model_module = __import__(model.__module__, fromlist=["shift_tokens_tight"])
+ shift_tokens_right_fn = getattr(model_module, "shift_tokens_right")
+
+ # Setting padding="max_length" as we need fixed length inputs for jitted functions
+ def preprocess_function(examples):
+ inputs = examples[text_column]
+ targets = examples[summary_column]
+ inputs = [prefix + inp for inp in inputs]
+ model_inputs = tokenizer(
+ inputs, max_length=data_args.max_source_length, padding="max_length", truncation=True, return_tensors="np"
+ )
+
+ # Setup the tokenizer for targets
+ labels = tokenizer(
+ text_target=targets,
+ max_length=max_target_length,
+ padding="max_length",
+ truncation=True,
+ return_tensors="np",
+ )
+
+ model_inputs["labels"] = labels["input_ids"]
+ decoder_input_ids = shift_tokens_right_fn(
+ labels["input_ids"], config.pad_token_id, config.decoder_start_token_id
+ )
+ model_inputs["decoder_input_ids"] = np.asarray(decoder_input_ids)
+
+ # We need decoder_attention_mask so we can ignore pad tokens from loss
+ model_inputs["decoder_attention_mask"] = labels["attention_mask"]
+
+ return model_inputs
+
+ if training_args.do_train:
+ train_dataset = dataset["train"]
+ if data_args.max_train_samples is not None:
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+ train_dataset = train_dataset.map(
+ preprocess_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on train dataset",
+ )
+
+ if training_args.do_eval:
+ max_target_length = data_args.val_max_target_length
+ eval_dataset = dataset["validation"]
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+ eval_dataset = eval_dataset.map(
+ preprocess_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on validation dataset",
+ )
+
+ if training_args.do_predict:
+ max_target_length = data_args.val_max_target_length
+ predict_dataset = dataset["test"]
+ if data_args.max_predict_samples is not None:
+ max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
+ predict_dataset = predict_dataset.select(range(max_predict_samples))
+ predict_dataset = predict_dataset.map(
+ preprocess_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on prediction dataset",
+ )
+
+ # Metric
+ metric = evaluate.load("rouge", cache_dir=model_args.cache_dir)
+
+ def postprocess_text(preds, labels):
+ preds = [pred.strip() for pred in preds]
+ labels = [label.strip() for label in labels]
+
+ # rougeLSum expects newline after each sentence
+ preds = ["\n".join(nltk.sent_tokenize(pred)) for pred in preds]
+ labels = ["\n".join(nltk.sent_tokenize(label)) for label in labels]
+
+ return preds, labels
+
+ def compute_metrics(preds, labels):
+ decoded_preds = tokenizer.batch_decode(preds, skip_special_tokens=True)
+ decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+ # Some simple post-processing
+ decoded_preds, decoded_labels = postprocess_text(decoded_preds, decoded_labels)
+
+ result = metric.compute(predictions=decoded_preds, references=decoded_labels, use_stemmer=True)
+ result = {k: round(v * 100, 4) for k, v in result.items()}
+ prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in preds]
+ result["gen_len"] = np.mean(prediction_lens)
+ return result
+
+ # Enable tensorboard only on the master node
+ has_tensorboard = is_tensorboard_available()
+ if has_tensorboard and jax.process_index() == 0:
+ try:
+ from flax.metrics.tensorboard import SummaryWriter
+
+ summary_writer = SummaryWriter(log_dir=Path(training_args.output_dir))
+ except ImportError as ie:
+ has_tensorboard = False
+ logger.warning(
+ f"Unable to display metrics through TensorBoard because some package are not installed: {ie}"
+ )
+ else:
+ logger.warning(
+ "Unable to display metrics through TensorBoard because the package is not installed: "
+ "Please run pip install tensorboard to enable."
+ )
+
+ # Initialize our training
+ rng = jax.random.PRNGKey(training_args.seed)
+ rng, dropout_rng = jax.random.split(rng)
+
+ # Store some constant
+ num_epochs = int(training_args.num_train_epochs)
+ train_batch_size = int(training_args.per_device_train_batch_size) * jax.device_count()
+ per_device_eval_batch_size = int(training_args.per_device_eval_batch_size)
+ eval_batch_size = per_device_eval_batch_size * jax.device_count()
+ steps_per_epoch = len(train_dataset) // train_batch_size
+ total_train_steps = steps_per_epoch * num_epochs
+
+ # Create learning rate schedule
+ linear_decay_lr_schedule_fn = create_learning_rate_fn(
+ len(train_dataset),
+ train_batch_size,
+ training_args.num_train_epochs,
+ training_args.warmup_steps,
+ training_args.learning_rate,
+ )
+
+ # We use Optax's "masking" functionality to not apply weight decay
+ # to bias and LayerNorm scale parameters. decay_mask_fn returns a
+ # mask boolean with the same structure as the parameters.
+ # The mask is True for parameters that should be decayed.
+ def decay_mask_fn(params):
+ flat_params = traverse_util.flatten_dict(params)
+ # find out all LayerNorm parameters
+ layer_norm_candidates = ["layernorm", "layer_norm", "ln"]
+ layer_norm_named_params = {
+ layer[-2:]
+ for layer_norm_name in layer_norm_candidates
+ for layer in flat_params.keys()
+ if layer_norm_name in "".join(layer).lower()
+ }
+ flat_mask = {path: (path[-1] != "bias" and path[-2:] not in layer_norm_named_params) for path in flat_params}
+ return traverse_util.unflatten_dict(flat_mask)
+
+ # create adam optimizer
+ adamw = optax.adamw(
+ learning_rate=linear_decay_lr_schedule_fn,
+ b1=training_args.adam_beta1,
+ b2=training_args.adam_beta2,
+ eps=training_args.adam_epsilon,
+ weight_decay=training_args.weight_decay,
+ mask=decay_mask_fn,
+ )
+
+ # Setup train state
+ state = TrainState.create(apply_fn=model.__call__, params=model.params, tx=adamw, dropout_rng=dropout_rng)
+
+ # label smoothed cross entropy
+ def loss_fn(logits, labels, padding_mask, label_smoothing_factor=0.0):
+ """
+ The label smoothing implementation is adapted from Flax's official example:
+ https://github.com/google/flax/blob/87a211135c6a377c8f29048a1cac3840e38b9da4/examples/wmt/train.py#L104
+ """
+ vocab_size = logits.shape[-1]
+ confidence = 1.0 - label_smoothing_factor
+ low_confidence = (1.0 - confidence) / (vocab_size - 1)
+ normalizing_constant = -(
+ confidence * jnp.log(confidence) + (vocab_size - 1) * low_confidence * jnp.log(low_confidence + 1e-20)
+ )
+ soft_labels = onehot(labels, vocab_size, on_value=confidence, off_value=low_confidence)
+
+ loss = optax.softmax_cross_entropy(logits, soft_labels)
+ loss = loss - normalizing_constant
+
+ # ignore padded tokens from loss
+ loss = loss * padding_mask
+ loss = loss.sum()
+ num_labels = padding_mask.sum()
+ return loss, num_labels
+
+ # Define gradient update step fn
+ def train_step(state, batch, label_smoothing_factor=0.0):
+ dropout_rng, new_dropout_rng = jax.random.split(state.dropout_rng)
+
+ def compute_loss(params):
+ labels = batch.pop("labels")
+ logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
+ loss, num_labels = loss_fn(logits, labels, batch["decoder_attention_mask"], label_smoothing_factor)
+ return loss, num_labels
+
+ grad_fn = jax.value_and_grad(compute_loss, has_aux=True)
+ (loss, num_labels), grad = grad_fn(state.params)
+ num_labels = jax.lax.psum(num_labels, "batch")
+
+ # true loss = total loss / total samples
+ loss = jax.lax.psum(loss, "batch")
+ loss = jax.tree_util.tree_map(lambda x: x / num_labels, loss)
+
+ # true grad = total grad / total samples
+ grad = jax.lax.psum(grad, "batch")
+ grad = jax.tree_util.tree_map(lambda x: x / num_labels, grad)
+ new_state = state.apply_gradients(grads=grad, dropout_rng=new_dropout_rng)
+
+ metrics = {"loss": loss, "learning_rate": linear_decay_lr_schedule_fn(state.step)}
+ return new_state, metrics
+
+ # Define eval fn
+ def eval_step(params, batch, label_smoothing_factor=0.0):
+ labels = batch.pop("labels")
+ logits = model(**batch, params=params, train=False)[0]
+
+ loss, num_labels = loss_fn(logits, labels, batch["decoder_attention_mask"], label_smoothing_factor)
+ num_labels = jax.lax.psum(num_labels, "batch")
+
+ # true loss = total loss / total samples
+ loss = jax.lax.psum(loss, "batch")
+ loss = jax.tree_util.tree_map(lambda x: x / num_labels, loss)
+
+ metrics = {"loss": loss}
+ return metrics
+
+ # Define generation function
+ max_length = (
+ data_args.val_max_target_length if data_args.val_max_target_length is not None else model.config.max_length
+ )
+ num_beams = data_args.num_beams if data_args.num_beams is not None else model.config.num_beams
+ gen_kwargs = {"max_length": max_length, "num_beams": num_beams}
+
+ def generate_step(params, batch):
+ model.params = params
+ output_ids = model.generate(batch["input_ids"], attention_mask=batch["attention_mask"], **gen_kwargs)
+ return output_ids.sequences
+
+ # Create parallel version of the train and eval step
+ p_train_step = jax.pmap(
+ partial(train_step, label_smoothing_factor=training_args.label_smoothing_factor), "batch", donate_argnums=(0,)
+ )
+ p_eval_step = jax.pmap(partial(eval_step, label_smoothing_factor=training_args.label_smoothing_factor), "batch")
+ p_generate_step = jax.pmap(generate_step, "batch")
+
+ # Replicate the train state on each device
+ state = state.replicate()
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {num_epochs}")
+ logger.info(f" Instantaneous batch size per device = {training_args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel & distributed) = {train_batch_size}")
+ logger.info(f" Total optimization steps = {total_train_steps}")
+
+ train_time = 0
+ epochs = tqdm(range(num_epochs), desc=f"Epoch ... (1/{num_epochs})", position=0)
+ for epoch in epochs:
+ # ======================== Training ================================
+ train_start = time.time()
+
+ # Create sampling rng
+ rng, input_rng = jax.random.split(rng)
+ train_metrics = []
+
+ # Generate an epoch by shuffling sampling indices from the train dataset
+ train_loader = data_loader(input_rng, train_dataset, train_batch_size, shuffle=True)
+ steps_per_epoch = len(train_dataset) // train_batch_size
+ # train
+ for _ in tqdm(range(steps_per_epoch), desc="Training...", position=1, leave=False):
+ batch = next(train_loader)
+ batch = shard(batch)
+ state, train_metric = p_train_step(state, batch)
+ train_metrics.append(train_metric)
+
+ train_time += time.time() - train_start
+
+ train_metric = unreplicate(train_metric)
+
+ epochs.write(
+ f"Epoch... ({epoch + 1}/{num_epochs} | Loss: {train_metric['loss']}, Learning Rate:"
+ f" {train_metric['learning_rate']})"
+ )
+
+ # ======================== Evaluating ==============================
+ eval_metrics = []
+ eval_preds = []
+ eval_labels = []
+
+ eval_loader = data_loader(input_rng, eval_dataset, eval_batch_size, drop_last=False)
+ eval_steps = math.ceil(len(eval_dataset) / eval_batch_size)
+ for _ in tqdm(range(eval_steps), desc="Evaluating...", position=2, leave=False):
+ # Model forward
+ batch = next(eval_loader)
+ labels = batch["labels"]
+
+ metrics = pad_shard_unpad(p_eval_step, static_return=True)(
+ state.params, batch, min_device_batch=per_device_eval_batch_size
+ )
+ eval_metrics.append(metrics)
+
+ # generation
+ if data_args.predict_with_generate:
+ generated_ids = pad_shard_unpad(p_generate_step)(state.params, batch)
+ eval_preds.extend(jax.device_get(generated_ids.reshape(-1, gen_kwargs["max_length"])))
+ eval_labels.extend(labels)
+
+ # normalize eval metrics
+ eval_metrics = get_metrics(eval_metrics)
+ eval_metrics = jax.tree_util.tree_map(jnp.mean, eval_metrics)
+
+ # compute ROUGE metrics
+ rouge_desc = ""
+ if data_args.predict_with_generate:
+ rouge_metrics = compute_metrics(eval_preds, eval_labels)
+ eval_metrics.update(rouge_metrics)
+ rouge_desc = " ".join([f"Eval {key}: {value} |" for key, value in rouge_metrics.items()])
+
+ # Print metrics and update progress bar
+ desc = f"Epoch... ({epoch + 1}/{num_epochs} | Eval Loss: {eval_metrics['loss']} | {rouge_desc})"
+ epochs.write(desc)
+ epochs.desc = desc
+
+ # Save metrics
+ if has_tensorboard and jax.process_index() == 0:
+ cur_step = epoch * (len(train_dataset) // train_batch_size)
+ write_metric(summary_writer, train_metrics, eval_metrics, train_time, cur_step)
+
+ # save checkpoint after each epoch and push checkpoint to the hub
+ if jax.process_index() == 0:
+ params = jax.device_get(jax.tree_util.tree_map(lambda x: x[0], state.params))
+ model.save_pretrained(training_args.output_dir, params=params)
+ tokenizer.save_pretrained(training_args.output_dir)
+ if training_args.push_to_hub:
+ api.upload_folder(
+ commit_message=f"Saving weights and logs of epoch {epoch}",
+ folder_path=training_args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=training_args.hub_token,
+ )
+
+ # ======================== Prediction loop ==============================
+ if training_args.do_predict:
+ logger.info("*** Predict ***")
+
+ pred_metrics = []
+ pred_generations = []
+ pred_labels = []
+
+ pred_loader = data_loader(input_rng, predict_dataset, eval_batch_size, drop_last=False)
+ pred_steps = math.ceil(len(predict_dataset) / eval_batch_size)
+ for _ in tqdm(range(pred_steps), desc="Predicting...", position=2, leave=False):
+ # Model forward
+ batch = next(pred_loader)
+ labels = batch["labels"]
+
+ metrics = pad_shard_unpad(p_eval_step, static_return=True)(
+ state.params, batch, min_device_batch=per_device_eval_batch_size
+ )
+ pred_metrics.append(metrics)
+
+ # generation
+ if data_args.predict_with_generate:
+ generated_ids = pad_shard_unpad(p_generate_step)(state.params, batch)
+ pred_generations.extend(jax.device_get(generated_ids.reshape(-1, gen_kwargs["max_length"])))
+ pred_labels.extend(labels)
+
+ # normalize prediction metrics
+ pred_metrics = get_metrics(pred_metrics)
+ pred_metrics = jax.tree_util.tree_map(jnp.mean, pred_metrics)
+
+ # compute ROUGE metrics
+ rouge_desc = ""
+ if data_args.predict_with_generate:
+ rouge_metrics = compute_metrics(pred_generations, pred_labels)
+ pred_metrics.update(rouge_metrics)
+ rouge_desc = " ".join([f"Predict {key}: {value} |" for key, value in rouge_metrics.items()])
+
+ # Print metrics
+ desc = f"Predict Loss: {pred_metrics['loss']} | {rouge_desc})"
+ logger.info(desc)
+
+ # save final metrics in json
+ if jax.process_index() == 0:
+ rouge_metrics = {f"test_{metric_name}": value for metric_name, value in rouge_metrics.items()}
+ path = os.path.join(training_args.output_dir, "test_results.json")
+ with open(path, "w") as f:
+ json.dump(rouge_metrics, f, indent=4, sort_keys=True)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/test_flax_examples.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/test_flax_examples.py
new file mode 100644
index 0000000000000000000000000000000000000000..c81d63781850703c22f6015d14b1f906764b2ee0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/test_flax_examples.py
@@ -0,0 +1,286 @@
+# coding=utf-8
+# Copyright 2021 HuggingFace Inc.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+
+import argparse
+import json
+import logging
+import os
+import sys
+from unittest.mock import patch
+
+from transformers.testing_utils import TestCasePlus, get_gpu_count, slow
+
+
+SRC_DIRS = [
+ os.path.join(os.path.dirname(__file__), dirname)
+ for dirname in [
+ "text-classification",
+ "language-modeling",
+ "summarization",
+ "token-classification",
+ "question-answering",
+ "speech-recognition",
+ ]
+]
+sys.path.extend(SRC_DIRS)
+
+
+if SRC_DIRS is not None:
+ import run_clm_flax
+ import run_flax_glue
+ import run_flax_ner
+ import run_flax_speech_recognition_seq2seq
+ import run_mlm_flax
+ import run_qa
+ import run_summarization_flax
+ import run_t5_mlm_flax
+
+
+logging.basicConfig(level=logging.DEBUG)
+
+logger = logging.getLogger()
+
+
+def get_setup_file():
+ parser = argparse.ArgumentParser()
+ parser.add_argument("-f")
+ args = parser.parse_args()
+ return args.f
+
+
+def get_results(output_dir, split="eval"):
+ path = os.path.join(output_dir, f"{split}_results.json")
+ if os.path.exists(path):
+ with open(path, "r") as f:
+ return json.load(f)
+ raise ValueError(f"can't find {path}")
+
+
+stream_handler = logging.StreamHandler(sys.stdout)
+logger.addHandler(stream_handler)
+
+
+class ExamplesTests(TestCasePlus):
+ def test_run_glue(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_glue.py
+ --model_name_or_path distilbert/distilbert-base-uncased
+ --output_dir {tmp_dir}
+ --train_file ./tests/fixtures/tests_samples/MRPC/train.csv
+ --validation_file ./tests/fixtures/tests_samples/MRPC/dev.csv
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --learning_rate=1e-4
+ --eval_steps=2
+ --warmup_steps=2
+ --seed=42
+ --max_seq_length=128
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ run_flax_glue.main()
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_accuracy"], 0.75)
+
+ @slow
+ def test_run_clm(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_clm_flax.py
+ --model_name_or_path distilbert/distilgpt2
+ --train_file ./tests/fixtures/sample_text.txt
+ --validation_file ./tests/fixtures/sample_text.txt
+ --do_train
+ --do_eval
+ --block_size 128
+ --per_device_train_batch_size 4
+ --per_device_eval_batch_size 4
+ --num_train_epochs 2
+ --logging_steps 2 --eval_steps 2
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ run_clm_flax.main()
+ result = get_results(tmp_dir)
+ self.assertLess(result["eval_perplexity"], 100)
+
+ @slow
+ def test_run_summarization(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_summarization.py
+ --model_name_or_path google-t5/t5-small
+ --train_file tests/fixtures/tests_samples/xsum/sample.json
+ --validation_file tests/fixtures/tests_samples/xsum/sample.json
+ --test_file tests/fixtures/tests_samples/xsum/sample.json
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ --num_train_epochs=3
+ --warmup_steps=8
+ --do_train
+ --do_eval
+ --do_predict
+ --learning_rate=2e-4
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --predict_with_generate
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ run_summarization_flax.main()
+ result = get_results(tmp_dir, split="test")
+ self.assertGreaterEqual(result["test_rouge1"], 10)
+ self.assertGreaterEqual(result["test_rouge2"], 2)
+ self.assertGreaterEqual(result["test_rougeL"], 7)
+ self.assertGreaterEqual(result["test_rougeLsum"], 7)
+
+ @slow
+ def test_run_mlm(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_mlm.py
+ --model_name_or_path distilbert/distilroberta-base
+ --train_file ./tests/fixtures/sample_text.txt
+ --validation_file ./tests/fixtures/sample_text.txt
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ --max_seq_length 128
+ --per_device_train_batch_size 4
+ --per_device_eval_batch_size 4
+ --logging_steps 2 --eval_steps 2
+ --do_train
+ --do_eval
+ --num_train_epochs=1
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ run_mlm_flax.main()
+ result = get_results(tmp_dir)
+ self.assertLess(result["eval_perplexity"], 42)
+
+ @slow
+ def test_run_t5_mlm(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_t5_mlm_flax.py
+ --model_name_or_path google-t5/t5-small
+ --train_file ./tests/fixtures/sample_text.txt
+ --validation_file ./tests/fixtures/sample_text.txt
+ --do_train
+ --do_eval
+ --max_seq_length 128
+ --per_device_train_batch_size 4
+ --per_device_eval_batch_size 4
+ --num_train_epochs 2
+ --logging_steps 2 --eval_steps 2
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ run_t5_mlm_flax.main()
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_accuracy"], 0.42)
+
+ @slow
+ def test_run_ner(self):
+ # with so little data distributed training needs more epochs to get the score on par with 0/1 gpu
+ epochs = 7 if get_gpu_count() > 1 else 2
+
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_flax_ner.py
+ --model_name_or_path google-bert/bert-base-uncased
+ --train_file tests/fixtures/tests_samples/conll/sample.json
+ --validation_file tests/fixtures/tests_samples/conll/sample.json
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ --do_train
+ --do_eval
+ --warmup_steps=2
+ --learning_rate=2e-4
+ --logging_steps 2 --eval_steps 2
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=2
+ --num_train_epochs={epochs}
+ --seed 7
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ run_flax_ner.main()
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_accuracy"], 0.75)
+ self.assertGreaterEqual(result["eval_f1"], 0.3)
+
+ @slow
+ def test_run_qa(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_qa.py
+ --model_name_or_path google-bert/bert-base-uncased
+ --version_2_with_negative
+ --train_file tests/fixtures/tests_samples/SQUAD/sample.json
+ --validation_file tests/fixtures/tests_samples/SQUAD/sample.json
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ --num_train_epochs=3
+ --warmup_steps=2
+ --do_train
+ --do_eval
+ --logging_steps 2 --eval_steps 2
+ --learning_rate=2e-4
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ run_qa.main()
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_f1"], 30)
+ self.assertGreaterEqual(result["eval_exact"], 30)
+
+ @slow
+ def test_run_flax_speech_recognition_seq2seq(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_flax_speech_recognition_seq2seq.py
+ --model_name_or_path openai/whisper-tiny.en
+ --dataset_name hf-internal-testing/librispeech_asr_dummy
+ --dataset_config clean
+ --train_split_name validation
+ --eval_split_name validation
+ --trust_remote_code
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ --num_train_epochs=2
+ --max_train_samples 10
+ --max_eval_samples 10
+ --warmup_steps=8
+ --do_train
+ --do_eval
+ --learning_rate=2e-4
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --predict_with_generate
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ run_flax_speech_recognition_seq2seq.main()
+ result = get_results(tmp_dir, split="eval")
+ self.assertLessEqual(result["eval_wer"], 0.05)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/text-classification/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/text-classification/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..65e50a075b78d59541093fe1fc830eb447e8d6ca
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/text-classification/README.md
@@ -0,0 +1,108 @@
+
+
+# Text classification examples
+
+## GLUE tasks
+
+Based on the script [`run_flax_glue.py`](https://github.com/huggingface/transformers/blob/main/examples/flax/text-classification/run_flax_glue.py).
+
+Fine-tuning the library models for sequence classification on the GLUE benchmark: [General Language Understanding
+Evaluation](https://gluebenchmark.com/). This script can fine-tune any of the models on the [hub](https://huggingface.co/models) and can also be used for a
+dataset hosted on our [hub](https://huggingface.co/datasets) or your own data in a csv or a JSON file (the script might need some tweaks in that case,
+refer to the comments inside for help).
+
+GLUE is made up of a total of 9 different tasks. Here is how to run the script on one of them:
+
+```bash
+export TASK_NAME=mrpc
+
+python run_flax_glue.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --task_name ${TASK_NAME} \
+ --max_seq_length 128 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3 \
+ --per_device_train_batch_size 4 \
+ --eval_steps 100 \
+ --output_dir ./$TASK_NAME/ \
+ --push_to_hub
+```
+
+where task name can be one of cola, mnli, mnli_mismatched, mnli_matched, mrpc, qnli, qqp, rte, sst2, stsb, wnli.
+
+Using the command above, the script will train for 3 epochs and run eval after each epoch.
+Metrics and hyperparameters are stored in Tensorflow event files in `--output_dir`.
+You can see the results by running `tensorboard` in that directory:
+
+```bash
+$ tensorboard --logdir .
+```
+
+or directly on the hub under *Training metrics*.
+
+### Accuracy Evaluation
+
+We train five replicas and report mean accuracy and stdev on the dev set below.
+We use the settings as in the command above (with an exception for MRPC and
+WNLI which are tiny and where we used 5 epochs instead of 3), and we use a total
+train batch size of 32 (we train on 8 Cloud v3 TPUs, so a per-device batch size of 4),
+
+On the task other than MRPC and WNLI we train for 3 these epochs because this is the standard,
+but looking at the training curves of some of them (e.g., SST-2, STS-b), it appears the models
+are undertrained and we could get better results when training longer.
+
+In the Tensorboard results linked below, the random seed of each model is equal to the ID of the run. So in order to reproduce run 1, run the command above with `--seed=1`. The best run used random seed 3, which is the default in the script. The results of all runs are in [this Google Sheet](https://docs.google.com/spreadsheets/d/1p3XzReMO75m_XdEJvPue-PIq_PN-96J2IJpJW1yS-10/edit?usp=sharing).
+
+| Task | Metric | Acc (best run) | Acc (avg/5runs) | Stdev | Metrics |
+|-------|------------------------------|----------------|-----------------|-----------|--------------------------------------------------------------------------|
+| CoLA | Matthews corr | 60.57 | 59.04 | 1.06 | [tfhub.dev](https://tensorboard.dev/experiment/lfr2adVpRtmLDALKrElkzg/) |
+| SST-2 | Accuracy | 92.66 | 92.23 | 0.57 | [tfhub.dev](https://tensorboard.dev/experiment/jYvfv2trRHKMjoWnXVwrZA/) |
+| MRPC | F1/Accuracy | 89.90/85.78 | 88.97/84.36 | 0.72/1.09 | [tfhub.dev](https://tensorboard.dev/experiment/bo3W3DEoRw2Q7YXjWrJkfg/) |
+| STS-B | Pearson/Spearman corr. | 89.04/88.70 | 88.94/88.63 | 0.07/0.07 | [tfhub.dev](https://tensorboard.dev/experiment/fxVwbLD7QpKhbot0r9rn2w/) |
+| QQP | Accuracy/F1 | 90.81/87.58 | 90.76/87.51 | 0.05/0.06 | [tfhub.dev](https://tensorboard.dev/experiment/di089Rc9TZmsnKRMrYNLsA/) |
+| MNLI | Matched acc. | 84.10 | 83.80 | 0.16 | [tfhub.dev](https://tensorboard.dev/experiment/JgNCGHDJSRaW6HBx6YQFYQ/) |
+| QNLI | Accuracy | 91.01 | 90.82 | 0.17 | [tfhub.dev](https://tensorboard.dev/experiment/Bq7cMGJnQMSggYgL8qNGeQ/) |
+| RTE | Accuracy | 66.06 | 64.76 | 1.04 | [tfhub.dev](https://tensorboard.dev/experiment/66Eq24bhRjqN6CEhgDSGqQ/) |
+| WNLI | Accuracy | 46.48 | 37.01 | 6.83 | [tfhub.dev](https://tensorboard.dev/experiment/TAqcnddqTkWvVEeGaWwIdQ/) |
+
+Some of these results are significantly different from the ones reported on the test set of GLUE benchmark on the
+website. For QQP and WNLI, please refer to [FAQ #12](https://gluebenchmark.com/faq) on the website.
+
+### Runtime evaluation
+
+We also ran each task once on a single V100 GPU, 8 V100 GPUs, and 8 Cloud v3 TPUs and report the
+overall training time below. For comparison we ran Pytorch's [run_glue.py](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-classification/run_glue.py) on a single GPU (last column).
+
+
+| Task | TPU v3-8 | 8 GPU | [1 GPU](https://tensorboard.dev/experiment/mkPS4Zh8TnGe1HB6Yzwj4Q) | 1 GPU (Pytorch) |
+|-------|-----------|------------|------------|-----------------|
+| CoLA | 1m 42s | 1m 26s | 3m 9s | 4m 6s |
+| SST-2 | 5m 12s | 6m 28s | 22m 33s | 34m 37s |
+| MRPC | 1m 29s | 1m 14s | 2m 20s | 2m 56s |
+| STS-B | 1m 30s | 1m 12s | 2m 16s | 2m 48s |
+| QQP | 22m 50s | 31m 48s | 1h 59m 41s | 2h 54m |
+| MNLI | 25m 03s | 33m 55s | 2h 9m 37s | 3h 7m 6s |
+| QNLI | 7m30s | 9m 40s | 34m 40s | 49m 8s |
+| RTE | 1m 20s | 55s | 1m 10s | 1m 16s |
+| WNLI | 1m 11s | 48s | 39s | 36s |
+|-------|
+| **TOTAL** | 1h 03m | 1h 28m | 5h 16m | 6h 37m |
+
+*All experiments are ran on Google Cloud Platform.
+GPU experiments are ran without further optimizations besides JAX
+transformations. GPU experiments are ran with full precision (fp32). "TPU v3-8"
+are 8 TPU cores on 4 chips (each chips has 2 cores), while "8 GPU" are 8 GPU chips.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/text-classification/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/text-classification/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..7507ae1b69c9aa60e4ad35f0b2ec2771b0ac8e39
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/text-classification/requirements.txt
@@ -0,0 +1,5 @@
+datasets >= 1.1.3
+jax>=0.2.8
+jaxlib>=0.1.59
+flax>=0.3.5
+optax>=0.0.8
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/text-classification/run_flax_glue.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/text-classification/run_flax_glue.py
new file mode 100644
index 0000000000000000000000000000000000000000..0c4edda3bd4afb901ea86208297de47b7c5ce243
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/text-classification/run_flax_glue.py
@@ -0,0 +1,698 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Finetuning a 🤗 Flax Transformers model for sequence classification on GLUE."""
+
+import json
+import logging
+import math
+import os
+import random
+import sys
+import time
+import warnings
+from dataclasses import dataclass, field
+from pathlib import Path
+from typing import Any, Callable, Dict, Optional, Tuple
+
+import datasets
+import evaluate
+import jax
+import jax.numpy as jnp
+import numpy as np
+import optax
+from datasets import load_dataset
+from flax import struct, traverse_util
+from flax.jax_utils import pad_shard_unpad, replicate, unreplicate
+from flax.training import train_state
+from flax.training.common_utils import get_metrics, onehot, shard
+from huggingface_hub import HfApi
+from tqdm import tqdm
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoTokenizer,
+ FlaxAutoModelForSequenceClassification,
+ HfArgumentParser,
+ PretrainedConfig,
+ TrainingArguments,
+ is_tensorboard_available,
+)
+from transformers.utils import check_min_version, send_example_telemetry
+
+
+logger = logging.getLogger(__name__)
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+Array = Any
+Dataset = datasets.arrow_dataset.Dataset
+PRNGKey = Any
+
+
+task_to_keys = {
+ "cola": ("sentence", None),
+ "mnli": ("premise", "hypothesis"),
+ "mrpc": ("sentence1", "sentence2"),
+ "qnli": ("question", "sentence"),
+ "qqp": ("question1", "question2"),
+ "rte": ("sentence1", "sentence2"),
+ "sst2": ("sentence", None),
+ "stsb": ("sentence1", "sentence2"),
+ "wnli": ("sentence1", "sentence2"),
+}
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ use_slow_tokenizer: Optional[bool] = field(
+ default=False,
+ metadata={"help": "If passed, will use a slow tokenizer (not backed by the 🤗 Tokenizers library)."},
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ use_auth_token: bool = field(
+ default=None,
+ metadata={
+ "help": "The `use_auth_token` argument is deprecated and will be removed in v4.34. Please use `token` instead."
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether or not to allow for custom models defined on the Hub in their own modeling files. This option "
+ "should only be set to `True` for repositories you trust and in which you have read the code, as it will "
+ "execute code present on the Hub on your local machine."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ task_name: Optional[str] = field(
+ default=None, metadata={"help": f"The name of the glue task to train on. choices {list(task_to_keys.keys())}"}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_file: Optional[str] = field(
+ default=None, metadata={"help": "The input training data file (a csv or JSON file)."}
+ )
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate on (a csv or JSON file)."},
+ )
+ test_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input test data file to predict on (a csv or JSON file)."},
+ )
+ text_column_name: Optional[str] = field(
+ default=None, metadata={"help": "The column name of text to input in the file (a csv or JSON file)."}
+ )
+ label_column_name: Optional[str] = field(
+ default=None, metadata={"help": "The column name of label to input in the file (a csv or JSON file)."}
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ max_seq_length: int = field(
+ default=None,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. If set, sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_predict_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of prediction examples to this "
+ "value if set."
+ )
+ },
+ )
+
+ def __post_init__(self):
+ if self.task_name is None and self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+ self.task_name = self.task_name.lower() if isinstance(self.task_name, str) else self.task_name
+
+
+def create_train_state(
+ model: FlaxAutoModelForSequenceClassification,
+ learning_rate_fn: Callable[[int], float],
+ is_regression: bool,
+ num_labels: int,
+ weight_decay: float,
+) -> train_state.TrainState:
+ """Create initial training state."""
+
+ class TrainState(train_state.TrainState):
+ """Train state with an Optax optimizer.
+
+ The two functions below differ depending on whether the task is classification
+ or regression.
+
+ Args:
+ logits_fn: Applied to last layer to obtain the logits.
+ loss_fn: Function to compute the loss.
+ """
+
+ logits_fn: Callable = struct.field(pytree_node=False)
+ loss_fn: Callable = struct.field(pytree_node=False)
+
+ # We use Optax's "masking" functionality to not apply weight decay
+ # to bias and LayerNorm scale parameters. decay_mask_fn returns a
+ # mask boolean with the same structure as the parameters.
+ # The mask is True for parameters that should be decayed.
+ def decay_mask_fn(params):
+ flat_params = traverse_util.flatten_dict(params)
+ # find out all LayerNorm parameters
+ layer_norm_candidates = ["layernorm", "layer_norm", "ln"]
+ layer_norm_named_params = {
+ layer[-2:]
+ for layer_norm_name in layer_norm_candidates
+ for layer in flat_params.keys()
+ if layer_norm_name in "".join(layer).lower()
+ }
+ flat_mask = {path: (path[-1] != "bias" and path[-2:] not in layer_norm_named_params) for path in flat_params}
+ return traverse_util.unflatten_dict(flat_mask)
+
+ tx = optax.adamw(
+ learning_rate=learning_rate_fn, b1=0.9, b2=0.999, eps=1e-6, weight_decay=weight_decay, mask=decay_mask_fn
+ )
+
+ if is_regression:
+
+ def mse_loss(logits, labels):
+ return jnp.mean((logits[..., 0] - labels) ** 2)
+
+ return TrainState.create(
+ apply_fn=model.__call__,
+ params=model.params,
+ tx=tx,
+ logits_fn=lambda logits: logits[..., 0],
+ loss_fn=mse_loss,
+ )
+ else: # Classification.
+
+ def cross_entropy_loss(logits, labels):
+ xentropy = optax.softmax_cross_entropy(logits, onehot(labels, num_classes=num_labels))
+ return jnp.mean(xentropy)
+
+ return TrainState.create(
+ apply_fn=model.__call__,
+ params=model.params,
+ tx=tx,
+ logits_fn=lambda logits: logits.argmax(-1),
+ loss_fn=cross_entropy_loss,
+ )
+
+
+def create_learning_rate_fn(
+ train_ds_size: int, train_batch_size: int, num_train_epochs: int, num_warmup_steps: int, learning_rate: float
+) -> Callable[[int], jnp.ndarray]:
+ """Returns a linear warmup, linear_decay learning rate function."""
+ steps_per_epoch = train_ds_size // train_batch_size
+ num_train_steps = steps_per_epoch * num_train_epochs
+ warmup_fn = optax.linear_schedule(init_value=0.0, end_value=learning_rate, transition_steps=num_warmup_steps)
+ decay_fn = optax.linear_schedule(
+ init_value=learning_rate, end_value=0, transition_steps=num_train_steps - num_warmup_steps
+ )
+ schedule_fn = optax.join_schedules(schedules=[warmup_fn, decay_fn], boundaries=[num_warmup_steps])
+ return schedule_fn
+
+
+def glue_train_data_collator(rng: PRNGKey, dataset: Dataset, batch_size: int):
+ """Returns shuffled batches of size `batch_size` from truncated `train dataset`, sharded over all local devices."""
+ steps_per_epoch = len(dataset) // batch_size
+ perms = jax.random.permutation(rng, len(dataset))
+ perms = perms[: steps_per_epoch * batch_size] # Skip incomplete batch.
+ perms = perms.reshape((steps_per_epoch, batch_size))
+
+ for perm in perms:
+ batch = dataset[perm]
+ batch = {k: np.array(v) for k, v in batch.items()}
+ batch = shard(batch)
+
+ yield batch
+
+
+def glue_eval_data_collator(dataset: Dataset, batch_size: int):
+ """Returns batches of size `batch_size` from `eval dataset`. Sharding handled by `pad_shard_unpad` in the eval loop."""
+ batch_idx = np.arange(len(dataset))
+
+ steps_per_epoch = math.ceil(len(dataset) / batch_size)
+ batch_idx = np.array_split(batch_idx, steps_per_epoch)
+
+ for idx in batch_idx:
+ batch = dataset[idx]
+ batch = {k: np.array(v) for k, v in batch.items()}
+
+ yield batch
+
+
+def main():
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ if model_args.use_auth_token is not None:
+ warnings.warn(
+ "The `use_auth_token` argument is deprecated and will be removed in v4.34. Please use `token` instead.",
+ FutureWarning,
+ )
+ if model_args.token is not None:
+ raise ValueError("`token` and `use_auth_token` are both specified. Please set only the argument `token`.")
+ model_args.token = model_args.use_auth_token
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_glue", model_args, data_args, framework="flax")
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ # Setup logging, we only want one process per machine to log things on the screen.
+ logger.setLevel(logging.INFO if jax.process_index() == 0 else logging.ERROR)
+ if jax.process_index() == 0:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # Handle the repository creation
+ if training_args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = training_args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(training_args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=training_args.hub_token).repo_id
+
+ # Get the datasets: you can either provide your own CSV/JSON training and evaluation files (see below)
+ # or specify a GLUE benchmark task (the dataset will be downloaded automatically from the datasets Hub).
+
+ # For CSV/JSON files, this script will use as labels the column called 'label' and as pair of sentences the
+ # sentences in columns called 'sentence1' and 'sentence2' if such column exists or the first two columns not named
+ # label if at least two columns are provided.
+
+ # If the CSVs/JSONs contain only one non-label column, the script does single sentence classification on this
+ # single column. You can easily tweak this behavior (see below)
+
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.task_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ "glue",
+ data_args.task_name,
+ token=model_args.token,
+ )
+ else:
+ # Loading the dataset from local csv or json file.
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = (data_args.train_file if data_args.train_file is not None else data_args.valid_file).split(".")[-1]
+ raw_datasets = load_dataset(
+ extension,
+ data_files=data_files,
+ token=model_args.token,
+ )
+ # See more about loading any type of standard or custom dataset at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Labels
+ if data_args.task_name is not None:
+ is_regression = data_args.task_name == "stsb"
+ if not is_regression:
+ label_list = raw_datasets["train"].features["label"].names
+ num_labels = len(label_list)
+ else:
+ num_labels = 1
+ else:
+ # Trying to have good defaults here, don't hesitate to tweak to your needs.
+ is_regression = raw_datasets["train"].features["label"].dtype in ["float32", "float64"]
+ if is_regression:
+ num_labels = 1
+ else:
+ # A useful fast method:
+ # https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Dataset.unique
+ label_list = raw_datasets["train"].unique("label")
+ label_list.sort() # Let's sort it for determinism
+ num_labels = len(label_list)
+
+ # Load pretrained model and tokenizer
+ config = AutoConfig.from_pretrained(
+ model_args.model_name_or_path,
+ num_labels=num_labels,
+ finetuning_task=data_args.task_name,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.model_name_or_path,
+ use_fast=not model_args.use_slow_tokenizer,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ model = FlaxAutoModelForSequenceClassification.from_pretrained(
+ model_args.model_name_or_path,
+ config=config,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ # Preprocessing the datasets
+ if data_args.task_name is not None:
+ sentence1_key, sentence2_key = task_to_keys[data_args.task_name]
+ else:
+ # Again, we try to have some nice defaults but don't hesitate to tweak to your use case.
+ non_label_column_names = [name for name in raw_datasets["train"].column_names if name != "label"]
+ if "sentence1" in non_label_column_names and "sentence2" in non_label_column_names:
+ sentence1_key, sentence2_key = "sentence1", "sentence2"
+ else:
+ if len(non_label_column_names) >= 2:
+ sentence1_key, sentence2_key = non_label_column_names[:2]
+ else:
+ sentence1_key, sentence2_key = non_label_column_names[0], None
+
+ # Some models have set the order of the labels to use, so let's make sure we do use it.
+ label_to_id = None
+ if (
+ model.config.label2id != PretrainedConfig(num_labels=num_labels).label2id
+ and data_args.task_name is not None
+ and not is_regression
+ ):
+ # Some have all caps in their config, some don't.
+ label_name_to_id = {k.lower(): v for k, v in model.config.label2id.items()}
+ if sorted(label_name_to_id.keys()) == sorted(label_list):
+ logger.info(
+ f"The configuration of the model provided the following label correspondence: {label_name_to_id}. "
+ "Using it!"
+ )
+ label_to_id = {i: label_name_to_id[label_list[i]] for i in range(num_labels)}
+ else:
+ logger.warning(
+ "Your model seems to have been trained with labels, but they don't match the dataset: "
+ f"model labels: {sorted(label_name_to_id.keys())}, dataset labels: {sorted(label_list)}."
+ "\nIgnoring the model labels as a result.",
+ )
+ elif data_args.task_name is None:
+ label_to_id = {v: i for i, v in enumerate(label_list)}
+
+ def preprocess_function(examples):
+ # Tokenize the texts
+ texts = (
+ (examples[sentence1_key],) if sentence2_key is None else (examples[sentence1_key], examples[sentence2_key])
+ )
+ result = tokenizer(*texts, padding="max_length", max_length=data_args.max_seq_length, truncation=True)
+
+ if "label" in examples:
+ if label_to_id is not None:
+ # Map labels to IDs (not necessary for GLUE tasks)
+ result["labels"] = [label_to_id[l] for l in examples["label"]]
+ else:
+ # In all cases, rename the column to labels because the model will expect that.
+ result["labels"] = examples["label"]
+ return result
+
+ processed_datasets = raw_datasets.map(
+ preprocess_function, batched=True, remove_columns=raw_datasets["train"].column_names
+ )
+
+ train_dataset = processed_datasets["train"]
+ eval_dataset = processed_datasets["validation_matched" if data_args.task_name == "mnli" else "validation"]
+
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ # Define a summary writer
+ has_tensorboard = is_tensorboard_available()
+ if has_tensorboard and jax.process_index() == 0:
+ try:
+ from flax.metrics.tensorboard import SummaryWriter
+
+ summary_writer = SummaryWriter(training_args.output_dir)
+ summary_writer.hparams({**training_args.to_dict(), **vars(model_args), **vars(data_args)})
+ except ImportError as ie:
+ has_tensorboard = False
+ logger.warning(
+ f"Unable to display metrics through TensorBoard because some package are not installed: {ie}"
+ )
+ else:
+ logger.warning(
+ "Unable to display metrics through TensorBoard because the package is not installed: "
+ "Please run pip install tensorboard to enable."
+ )
+
+ def write_train_metric(summary_writer, train_metrics, train_time, step):
+ summary_writer.scalar("train_time", train_time, step)
+
+ train_metrics = get_metrics(train_metrics)
+ for key, vals in train_metrics.items():
+ tag = f"train_{key}"
+ for i, val in enumerate(vals):
+ summary_writer.scalar(tag, val, step - len(vals) + i + 1)
+
+ def write_eval_metric(summary_writer, eval_metrics, step):
+ for metric_name, value in eval_metrics.items():
+ summary_writer.scalar(f"eval_{metric_name}", value, step)
+
+ num_epochs = int(training_args.num_train_epochs)
+ rng = jax.random.PRNGKey(training_args.seed)
+ dropout_rngs = jax.random.split(rng, jax.local_device_count())
+
+ train_batch_size = int(training_args.per_device_train_batch_size) * jax.local_device_count()
+ per_device_eval_batch_size = int(training_args.per_device_eval_batch_size)
+ eval_batch_size = per_device_eval_batch_size * jax.device_count()
+
+ learning_rate_fn = create_learning_rate_fn(
+ len(train_dataset),
+ train_batch_size,
+ training_args.num_train_epochs,
+ training_args.warmup_steps,
+ training_args.learning_rate,
+ )
+
+ state = create_train_state(
+ model, learning_rate_fn, is_regression, num_labels=num_labels, weight_decay=training_args.weight_decay
+ )
+
+ # define step functions
+ def train_step(
+ state: train_state.TrainState, batch: Dict[str, Array], dropout_rng: PRNGKey
+ ) -> Tuple[train_state.TrainState, float]:
+ """Trains model with an optimizer (both in `state`) on `batch`, returning a pair `(new_state, loss)`."""
+ dropout_rng, new_dropout_rng = jax.random.split(dropout_rng)
+ targets = batch.pop("labels")
+
+ def loss_fn(params):
+ logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
+ loss = state.loss_fn(logits, targets)
+ return loss
+
+ grad_fn = jax.value_and_grad(loss_fn)
+ loss, grad = grad_fn(state.params)
+ grad = jax.lax.pmean(grad, "batch")
+ new_state = state.apply_gradients(grads=grad)
+ metrics = jax.lax.pmean({"loss": loss, "learning_rate": learning_rate_fn(state.step)}, axis_name="batch")
+ return new_state, metrics, new_dropout_rng
+
+ p_train_step = jax.pmap(train_step, axis_name="batch", donate_argnums=(0,))
+
+ def eval_step(state, batch):
+ logits = state.apply_fn(**batch, params=state.params, train=False)[0]
+ return state.logits_fn(logits)
+
+ p_eval_step = jax.pmap(eval_step, axis_name="batch")
+
+ if data_args.task_name is not None:
+ metric = evaluate.load("glue", data_args.task_name, cache_dir=model_args.cache_dir)
+ else:
+ metric = evaluate.load("accuracy", cache_dir=model_args.cache_dir)
+
+ logger.info(f"===== Starting training ({num_epochs} epochs) =====")
+ train_time = 0
+
+ # make sure weights are replicated on each device
+ state = replicate(state)
+
+ steps_per_epoch = len(train_dataset) // train_batch_size
+ total_steps = steps_per_epoch * num_epochs
+ epochs = tqdm(range(num_epochs), desc=f"Epoch ... (0/{num_epochs})", position=0)
+ for epoch in epochs:
+ train_start = time.time()
+ train_metrics = []
+
+ # Create sampling rng
+ rng, input_rng = jax.random.split(rng)
+
+ # train
+ train_loader = glue_train_data_collator(input_rng, train_dataset, train_batch_size)
+ for step, batch in enumerate(
+ tqdm(
+ train_loader,
+ total=steps_per_epoch,
+ desc="Training...",
+ position=1,
+ ),
+ ):
+ state, train_metric, dropout_rngs = p_train_step(state, batch, dropout_rngs)
+ train_metrics.append(train_metric)
+
+ cur_step = (epoch * steps_per_epoch) + (step + 1)
+
+ if cur_step % training_args.logging_steps == 0 and cur_step > 0:
+ # Save metrics
+ train_metric = unreplicate(train_metric)
+ train_time += time.time() - train_start
+ if has_tensorboard and jax.process_index() == 0:
+ write_train_metric(summary_writer, train_metrics, train_time, cur_step)
+
+ epochs.write(
+ f"Step... ({cur_step}/{total_steps} | Training Loss: {train_metric['loss']}, Learning Rate:"
+ f" {train_metric['learning_rate']})"
+ )
+
+ train_metrics = []
+
+ if (cur_step % training_args.eval_steps == 0 or cur_step % steps_per_epoch == 0) and cur_step > 0:
+ # evaluate
+ eval_loader = glue_eval_data_collator(eval_dataset, eval_batch_size)
+ for batch in tqdm(
+ eval_loader,
+ total=math.ceil(len(eval_dataset) / eval_batch_size),
+ desc="Evaluating ...",
+ position=2,
+ ):
+ labels = batch.pop("labels")
+ predictions = pad_shard_unpad(p_eval_step)(
+ state, batch, min_device_batch=per_device_eval_batch_size
+ )
+ metric.add_batch(predictions=np.array(predictions), references=labels)
+
+ eval_metric = metric.compute()
+
+ logger.info(f"Step... ({cur_step}/{total_steps} | Eval metrics: {eval_metric})")
+
+ if has_tensorboard and jax.process_index() == 0:
+ write_eval_metric(summary_writer, eval_metric, cur_step)
+
+ if (cur_step % training_args.save_steps == 0 and cur_step > 0) or (cur_step == total_steps):
+ # save checkpoint after each epoch and push checkpoint to the hub
+ if jax.process_index() == 0:
+ params = jax.device_get(unreplicate(state.params))
+ model.save_pretrained(training_args.output_dir, params=params)
+ tokenizer.save_pretrained(training_args.output_dir)
+ if training_args.push_to_hub:
+ api.upload_folder(
+ commit_message=f"Saving weights and logs of epoch {epoch}",
+ folder_path=training_args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=training_args.hub_token,
+ )
+ epochs.desc = f"Epoch ... {epoch + 1}/{num_epochs}"
+
+ # save the eval metrics in json
+ if jax.process_index() == 0:
+ eval_metric = {f"eval_{metric_name}": value for metric_name, value in eval_metric.items()}
+ path = os.path.join(training_args.output_dir, "eval_results.json")
+ with open(path, "w") as f:
+ json.dump(eval_metric, f, indent=4, sort_keys=True)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/token-classification/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/token-classification/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..1f8175072148bbbe9fc9aa884616589104e05ed5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/token-classification/README.md
@@ -0,0 +1,49 @@
+
+
+# Token classification examples
+
+Fine-tuning the library models for token classification task such as Named Entity Recognition (NER), Parts-of-speech tagging (POS) or phrase extraction (CHUNKS). The main script run_flax_ner.py leverages the 🤗 Datasets library. You can easily customize it to your needs if you need extra processing on your datasets.
+
+It will either run on a datasets hosted on our hub or with your own text files for training and validation, you might just need to add some tweaks in the data preprocessing.
+
+The following example fine-tunes BERT on CoNLL-2003:
+
+
+```bash
+python run_flax_ner.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --dataset_name conll2003 \
+ --max_seq_length 128 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3 \
+ --per_device_train_batch_size 4 \
+ --output_dir ./bert-ner-conll2003 \
+ --eval_steps 300 \
+ --push_to_hub
+```
+
+Using the command above, the script will train for 3 epochs and run eval after each epoch.
+Metrics and hyperparameters are stored in Tensorflow event files in `--output_dir`.
+You can see the results by running `tensorboard` in that directory:
+
+```bash
+$ tensorboard --logdir .
+```
+
+or directly on the hub under *Training metrics*.
+
+sample Metrics - [tfhub.dev](https://tensorboard.dev/experiment/u52qsBIpQSKEEXEJd2LVYA)
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/token-classification/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/token-classification/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..f5ae92023d0c41158dd73931a1dc9ba0d5b80e25
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/token-classification/requirements.txt
@@ -0,0 +1,6 @@
+datasets >= 1.8.0
+jax>=0.2.8
+jaxlib>=0.1.59
+flax>=0.3.5
+optax>=0.0.8
+seqeval
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/token-classification/run_flax_ner.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/token-classification/run_flax_ner.py
new file mode 100644
index 0000000000000000000000000000000000000000..bc83fb53e2120e1109f2aba6ae0dee493ae7d95f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/token-classification/run_flax_ner.py
@@ -0,0 +1,833 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fine-tuning a 🤗 Flax Transformers model on token classification tasks (NER, POS, CHUNKS)"""
+
+import json
+import logging
+import math
+import os
+import random
+import sys
+import time
+import warnings
+from dataclasses import asdict, dataclass, field
+from enum import Enum
+from itertools import chain
+from pathlib import Path
+from typing import Any, Callable, Dict, Optional, Tuple
+
+import datasets
+import evaluate
+import jax
+import jax.numpy as jnp
+import numpy as np
+import optax
+from datasets import ClassLabel, load_dataset
+from flax import struct, traverse_util
+from flax.jax_utils import pad_shard_unpad, replicate, unreplicate
+from flax.training import train_state
+from flax.training.common_utils import get_metrics, onehot, shard
+from huggingface_hub import HfApi
+from tqdm import tqdm
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoTokenizer,
+ FlaxAutoModelForTokenClassification,
+ HfArgumentParser,
+ is_tensorboard_available,
+)
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+logger = logging.getLogger(__name__)
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/token-classification/requirements.txt")
+
+Array = Any
+Dataset = datasets.arrow_dataset.Dataset
+PRNGKey = Any
+
+
+@dataclass
+class TrainingArguments:
+ output_dir: str = field(
+ metadata={"help": "The output directory where the model predictions and checkpoints will be written."},
+ )
+ overwrite_output_dir: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Overwrite the content of the output directory. "
+ "Use this to continue training if output_dir points to a checkpoint directory."
+ )
+ },
+ )
+ do_train: bool = field(default=False, metadata={"help": "Whether to run training."})
+ do_eval: bool = field(default=False, metadata={"help": "Whether to run eval on the dev set."})
+ per_device_train_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for training."}
+ )
+ per_device_eval_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for evaluation."}
+ )
+ learning_rate: float = field(default=5e-5, metadata={"help": "The initial learning rate for AdamW."})
+ weight_decay: float = field(default=0.0, metadata={"help": "Weight decay for AdamW if we apply some."})
+ adam_beta1: float = field(default=0.9, metadata={"help": "Beta1 for AdamW optimizer"})
+ adam_beta2: float = field(default=0.999, metadata={"help": "Beta2 for AdamW optimizer"})
+ adam_epsilon: float = field(default=1e-8, metadata={"help": "Epsilon for AdamW optimizer."})
+ adafactor: bool = field(default=False, metadata={"help": "Whether or not to replace AdamW by Adafactor."})
+ num_train_epochs: float = field(default=3.0, metadata={"help": "Total number of training epochs to perform."})
+ warmup_steps: int = field(default=0, metadata={"help": "Linear warmup over warmup_steps."})
+ logging_steps: int = field(default=500, metadata={"help": "Log every X updates steps."})
+ save_steps: int = field(default=500, metadata={"help": "Save checkpoint every X updates steps."})
+ eval_steps: int = field(default=None, metadata={"help": "Run an evaluation every X steps."})
+ seed: int = field(default=42, metadata={"help": "Random seed that will be set at the beginning of training."})
+ push_to_hub: bool = field(
+ default=False, metadata={"help": "Whether or not to upload the trained model to the model hub after training."}
+ )
+ hub_model_id: str = field(
+ default=None, metadata={"help": "The name of the repository to keep in sync with the local `output_dir`."}
+ )
+ hub_token: str = field(default=None, metadata={"help": "The token to use to push to the Model Hub."})
+
+ def __post_init__(self):
+ if self.output_dir is not None:
+ self.output_dir = os.path.expanduser(self.output_dir)
+
+ def to_dict(self):
+ """
+ Serializes this instance while replace `Enum` by their values (for JSON serialization support). It obfuscates
+ the token values by removing their value.
+ """
+ d = asdict(self)
+ for k, v in d.items():
+ if isinstance(v, Enum):
+ d[k] = v.value
+ if isinstance(v, list) and len(v) > 0 and isinstance(v[0], Enum):
+ d[k] = [x.value for x in v]
+ if k.endswith("_token"):
+ d[k] = f"<{k.upper()}>"
+ return d
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ use_auth_token: bool = field(
+ default=None,
+ metadata={
+ "help": "The `use_auth_token` argument is deprecated and will be removed in v4.34. Please use `token` instead."
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ task_name: Optional[str] = field(default="ner", metadata={"help": "The name of the task (ner, pos...)."})
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_file: Optional[str] = field(
+ default=None, metadata={"help": "The input training data file (a csv or JSON file)."}
+ )
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate on (a csv or JSON file)."},
+ )
+ test_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input test data file to predict on (a csv or JSON file)."},
+ )
+ text_column_name: Optional[str] = field(
+ default=None, metadata={"help": "The column name of text to input in the file (a csv or JSON file)."}
+ )
+ label_column_name: Optional[str] = field(
+ default=None, metadata={"help": "The column name of label to input in the file (a csv or JSON file)."}
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ max_seq_length: int = field(
+ default=None,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. If set, sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_predict_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of prediction examples to this "
+ "value if set."
+ )
+ },
+ )
+ label_all_tokens: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to put the label for one word on all tokens of generated by that word or just on the "
+ "one (in which case the other tokens will have a padding index)."
+ )
+ },
+ )
+ return_entity_level_metrics: bool = field(
+ default=False,
+ metadata={"help": "Whether to return all the entity levels during evaluation or just the overall ones."},
+ )
+
+ def __post_init__(self):
+ if self.dataset_name is None and self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+ self.task_name = self.task_name.lower()
+
+
+def create_train_state(
+ model: FlaxAutoModelForTokenClassification,
+ learning_rate_fn: Callable[[int], float],
+ num_labels: int,
+ training_args: TrainingArguments,
+) -> train_state.TrainState:
+ """Create initial training state."""
+
+ class TrainState(train_state.TrainState):
+ """Train state with an Optax optimizer.
+
+ The two functions below differ depending on whether the task is classification
+ or regression.
+
+ Args:
+ logits_fn: Applied to last layer to obtain the logits.
+ loss_fn: Function to compute the loss.
+ """
+
+ logits_fn: Callable = struct.field(pytree_node=False)
+ loss_fn: Callable = struct.field(pytree_node=False)
+
+ # We use Optax's "masking" functionality to not apply weight decay
+ # to bias and LayerNorm scale parameters. decay_mask_fn returns a
+ # mask boolean with the same structure as the parameters.
+ # The mask is True for parameters that should be decayed.
+ def decay_mask_fn(params):
+ flat_params = traverse_util.flatten_dict(params)
+ # find out all LayerNorm parameters
+ layer_norm_candidates = ["layernorm", "layer_norm", "ln"]
+ layer_norm_named_params = {
+ layer[-2:]
+ for layer_norm_name in layer_norm_candidates
+ for layer in flat_params.keys()
+ if layer_norm_name in "".join(layer).lower()
+ }
+ flat_mask = {path: (path[-1] != "bias" and path[-2:] not in layer_norm_named_params) for path in flat_params}
+ return traverse_util.unflatten_dict(flat_mask)
+
+ tx = optax.adamw(
+ learning_rate=learning_rate_fn,
+ b1=training_args.adam_beta1,
+ b2=training_args.adam_beta2,
+ eps=training_args.adam_epsilon,
+ weight_decay=training_args.weight_decay,
+ mask=decay_mask_fn,
+ )
+
+ def cross_entropy_loss(logits, labels):
+ xentropy = optax.softmax_cross_entropy(logits, onehot(labels, num_classes=num_labels))
+ return jnp.mean(xentropy)
+
+ return TrainState.create(
+ apply_fn=model.__call__,
+ params=model.params,
+ tx=tx,
+ logits_fn=lambda logits: logits.argmax(-1),
+ loss_fn=cross_entropy_loss,
+ )
+
+
+def create_learning_rate_fn(
+ train_ds_size: int, train_batch_size: int, num_train_epochs: int, num_warmup_steps: int, learning_rate: float
+) -> Callable[[int], jnp.ndarray]:
+ """Returns a linear warmup, linear_decay learning rate function."""
+ steps_per_epoch = train_ds_size // train_batch_size
+ num_train_steps = steps_per_epoch * num_train_epochs
+ warmup_fn = optax.linear_schedule(init_value=0.0, end_value=learning_rate, transition_steps=num_warmup_steps)
+ decay_fn = optax.linear_schedule(
+ init_value=learning_rate, end_value=0, transition_steps=num_train_steps - num_warmup_steps
+ )
+ schedule_fn = optax.join_schedules(schedules=[warmup_fn, decay_fn], boundaries=[num_warmup_steps])
+ return schedule_fn
+
+
+def train_data_collator(rng: PRNGKey, dataset: Dataset, batch_size: int):
+ """Returns shuffled batches of size `batch_size` from truncated `train dataset`, sharded over all local devices."""
+ steps_per_epoch = len(dataset) // batch_size
+ perms = jax.random.permutation(rng, len(dataset))
+ perms = perms[: steps_per_epoch * batch_size] # Skip incomplete batch.
+ perms = perms.reshape((steps_per_epoch, batch_size))
+
+ for perm in perms:
+ batch = dataset[perm]
+ batch = {k: np.array(v) for k, v in batch.items()}
+ batch = shard(batch)
+
+ yield batch
+
+
+def eval_data_collator(dataset: Dataset, batch_size: int):
+ """Returns batches of size `batch_size` from `eval dataset`. Sharding handled by `pad_shard_unpad` in the eval loop."""
+ batch_idx = np.arange(len(dataset))
+
+ steps_per_epoch = math.ceil(len(dataset) / batch_size)
+ batch_idx = np.array_split(batch_idx, steps_per_epoch)
+
+ for idx in batch_idx:
+ batch = dataset[idx]
+ batch = {k: np.array(v) for k, v in batch.items()}
+
+ yield batch
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ if model_args.use_auth_token is not None:
+ warnings.warn(
+ "The `use_auth_token` argument is deprecated and will be removed in v4.34. Please use `token` instead.",
+ FutureWarning,
+ )
+ if model_args.token is not None:
+ raise ValueError("`token` and `use_auth_token` are both specified. Please set only the argument `token`.")
+ model_args.token = model_args.use_auth_token
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_ner", model_args, data_args, framework="flax")
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ # Setup logging, we only want one process per machine to log things on the screen.
+ logger.setLevel(logging.INFO if jax.process_index() == 0 else logging.ERROR)
+ if jax.process_index() == 0:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # Handle the repository creation
+ if training_args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = training_args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(training_args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=training_args.hub_token).repo_id
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets for token classification task available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'tokens' or the first column if no column called
+ # 'tokens' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ # Loading the dataset from local csv or json file.
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = (data_args.train_file if data_args.train_file is not None else data_args.valid_file).split(".")[-1]
+ raw_datasets = load_dataset(
+ extension,
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ # See more about loading any type of standard or custom dataset at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ if raw_datasets["train"] is not None:
+ column_names = raw_datasets["train"].column_names
+ features = raw_datasets["train"].features
+ else:
+ column_names = raw_datasets["validation"].column_names
+ features = raw_datasets["validation"].features
+
+ if data_args.text_column_name is not None:
+ text_column_name = data_args.text_column_name
+ elif "tokens" in column_names:
+ text_column_name = "tokens"
+ else:
+ text_column_name = column_names[0]
+
+ if data_args.label_column_name is not None:
+ label_column_name = data_args.label_column_name
+ elif f"{data_args.task_name}_tags" in column_names:
+ label_column_name = f"{data_args.task_name}_tags"
+ else:
+ label_column_name = column_names[1]
+
+ # In the event the labels are not a `Sequence[ClassLabel]`, we will need to go through the dataset to get the
+ # unique labels.
+ def get_label_list(labels):
+ unique_labels = set()
+ for label in labels:
+ unique_labels = unique_labels | set(label)
+ label_list = list(unique_labels)
+ label_list.sort()
+ return label_list
+
+ if isinstance(features[label_column_name].feature, ClassLabel):
+ label_list = features[label_column_name].feature.names
+ # No need to convert the labels since they are already ints.
+ label_to_id = {i: i for i in range(len(label_list))}
+ else:
+ label_list = get_label_list(raw_datasets["train"][label_column_name])
+ label_to_id = {l: i for i, l in enumerate(label_list)}
+ num_labels = len(label_list)
+
+ # Load pretrained model and tokenizer
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ num_labels=num_labels,
+ label2id=label_to_id,
+ id2label={i: l for l, i in label_to_id.items()},
+ finetuning_task=data_args.task_name,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ tokenizer_name_or_path = model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path
+ if config.model_type in {"gpt2", "roberta"}:
+ tokenizer = AutoTokenizer.from_pretrained(
+ tokenizer_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ add_prefix_space=True,
+ )
+ else:
+ tokenizer = AutoTokenizer.from_pretrained(
+ tokenizer_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ model = FlaxAutoModelForTokenClassification.from_pretrained(
+ model_args.model_name_or_path,
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ # Preprocessing the datasets
+ # Tokenize all texts and align the labels with them.
+ def tokenize_and_align_labels(examples):
+ tokenized_inputs = tokenizer(
+ examples[text_column_name],
+ max_length=data_args.max_seq_length,
+ padding="max_length",
+ truncation=True,
+ # We use this argument because the texts in our dataset are lists of words (with a label for each word).
+ is_split_into_words=True,
+ )
+
+ labels = []
+
+ for i, label in enumerate(examples[label_column_name]):
+ word_ids = tokenized_inputs.word_ids(batch_index=i)
+ previous_word_idx = None
+ label_ids = []
+ for word_idx in word_ids:
+ # Special tokens have a word id that is None. We set the label to -100 so they are automatically
+ # ignored in the loss function.
+ if word_idx is None:
+ label_ids.append(-100)
+ # We set the label for the first token of each word.
+ elif word_idx != previous_word_idx:
+ label_ids.append(label_to_id[label[word_idx]])
+ # For the other tokens in a word, we set the label to either the current label or -100, depending on
+ # the label_all_tokens flag.
+ else:
+ label_ids.append(label_to_id[label[word_idx]] if data_args.label_all_tokens else -100)
+ previous_word_idx = word_idx
+
+ labels.append(label_ids)
+ tokenized_inputs["labels"] = labels
+ return tokenized_inputs
+
+ processed_raw_datasets = raw_datasets.map(
+ tokenize_and_align_labels,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ remove_columns=raw_datasets["train"].column_names,
+ desc="Running tokenizer on dataset",
+ )
+
+ train_dataset = processed_raw_datasets["train"]
+ eval_dataset = processed_raw_datasets["validation"]
+
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ # Define a summary writer
+ has_tensorboard = is_tensorboard_available()
+ if has_tensorboard and jax.process_index() == 0:
+ try:
+ from flax.metrics.tensorboard import SummaryWriter
+
+ summary_writer = SummaryWriter(training_args.output_dir)
+ summary_writer.hparams({**training_args.to_dict(), **vars(model_args), **vars(data_args)})
+ except ImportError as ie:
+ has_tensorboard = False
+ logger.warning(
+ f"Unable to display metrics through TensorBoard because some package are not installed: {ie}"
+ )
+ else:
+ logger.warning(
+ "Unable to display metrics through TensorBoard because the package is not installed: "
+ "Please run pip install tensorboard to enable."
+ )
+
+ def write_train_metric(summary_writer, train_metrics, train_time, step):
+ summary_writer.scalar("train_time", train_time, step)
+
+ train_metrics = get_metrics(train_metrics)
+ for key, vals in train_metrics.items():
+ tag = f"train_{key}"
+ for i, val in enumerate(vals):
+ summary_writer.scalar(tag, val, step - len(vals) + i + 1)
+
+ def write_eval_metric(summary_writer, eval_metrics, step):
+ for metric_name, value in eval_metrics.items():
+ summary_writer.scalar(f"eval_{metric_name}", value, step)
+
+ num_epochs = int(training_args.num_train_epochs)
+ rng = jax.random.PRNGKey(training_args.seed)
+ dropout_rngs = jax.random.split(rng, jax.local_device_count())
+
+ train_batch_size = training_args.per_device_train_batch_size * jax.local_device_count()
+ per_device_eval_batch_size = int(training_args.per_device_eval_batch_size)
+ eval_batch_size = training_args.per_device_eval_batch_size * jax.local_device_count()
+
+ learning_rate_fn = create_learning_rate_fn(
+ len(train_dataset),
+ train_batch_size,
+ training_args.num_train_epochs,
+ training_args.warmup_steps,
+ training_args.learning_rate,
+ )
+
+ state = create_train_state(model, learning_rate_fn, num_labels=num_labels, training_args=training_args)
+
+ # define step functions
+ def train_step(
+ state: train_state.TrainState, batch: Dict[str, Array], dropout_rng: PRNGKey
+ ) -> Tuple[train_state.TrainState, float]:
+ """Trains model with an optimizer (both in `state`) on `batch`, returning a pair `(new_state, loss)`."""
+ dropout_rng, new_dropout_rng = jax.random.split(dropout_rng)
+ targets = batch.pop("labels")
+
+ def loss_fn(params):
+ logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
+ loss = state.loss_fn(logits, targets)
+ return loss
+
+ grad_fn = jax.value_and_grad(loss_fn)
+ loss, grad = grad_fn(state.params)
+ grad = jax.lax.pmean(grad, "batch")
+ new_state = state.apply_gradients(grads=grad)
+ metrics = jax.lax.pmean({"loss": loss, "learning_rate": learning_rate_fn(state.step)}, axis_name="batch")
+ return new_state, metrics, new_dropout_rng
+
+ p_train_step = jax.pmap(train_step, axis_name="batch", donate_argnums=(0,))
+
+ def eval_step(state, batch):
+ logits = state.apply_fn(**batch, params=state.params, train=False)[0]
+ return state.logits_fn(logits)
+
+ p_eval_step = jax.pmap(eval_step, axis_name="batch")
+
+ metric = evaluate.load("seqeval", cache_dir=model_args.cache_dir)
+
+ def get_labels(y_pred, y_true):
+ # Transform predictions and references tensos to numpy arrays
+
+ # Remove ignored index (special tokens)
+ true_predictions = [
+ [label_list[p] for (p, l) in zip(pred, gold_label) if l != -100]
+ for pred, gold_label in zip(y_pred, y_true)
+ ]
+ true_labels = [
+ [label_list[l] for (p, l) in zip(pred, gold_label) if l != -100]
+ for pred, gold_label in zip(y_pred, y_true)
+ ]
+ return true_predictions, true_labels
+
+ def compute_metrics():
+ results = metric.compute()
+ if data_args.return_entity_level_metrics:
+ # Unpack nested dictionaries
+ final_results = {}
+ for key, value in results.items():
+ if isinstance(value, dict):
+ for n, v in value.items():
+ final_results[f"{key}_{n}"] = v
+ else:
+ final_results[key] = value
+ return final_results
+ else:
+ return {
+ "precision": results["overall_precision"],
+ "recall": results["overall_recall"],
+ "f1": results["overall_f1"],
+ "accuracy": results["overall_accuracy"],
+ }
+
+ logger.info(f"===== Starting training ({num_epochs} epochs) =====")
+ train_time = 0
+
+ # make sure weights are replicated on each device
+ state = replicate(state)
+
+ train_time = 0
+ step_per_epoch = len(train_dataset) // train_batch_size
+ total_steps = step_per_epoch * num_epochs
+ epochs = tqdm(range(num_epochs), desc=f"Epoch ... (1/{num_epochs})", position=0)
+ for epoch in epochs:
+ train_start = time.time()
+ train_metrics = []
+
+ # Create sampling rng
+ rng, input_rng = jax.random.split(rng)
+
+ # train
+ for step, batch in enumerate(
+ tqdm(
+ train_data_collator(input_rng, train_dataset, train_batch_size),
+ total=step_per_epoch,
+ desc="Training...",
+ position=1,
+ )
+ ):
+ state, train_metric, dropout_rngs = p_train_step(state, batch, dropout_rngs)
+ train_metrics.append(train_metric)
+
+ cur_step = (epoch * step_per_epoch) + (step + 1)
+
+ if cur_step % training_args.logging_steps == 0 and cur_step > 0:
+ # Save metrics
+ train_metric = unreplicate(train_metric)
+ train_time += time.time() - train_start
+ if has_tensorboard and jax.process_index() == 0:
+ write_train_metric(summary_writer, train_metrics, train_time, cur_step)
+
+ epochs.write(
+ f"Step... ({cur_step}/{total_steps} | Training Loss: {train_metric['loss']}, Learning Rate:"
+ f" {train_metric['learning_rate']})"
+ )
+
+ train_metrics = []
+
+ if cur_step % training_args.eval_steps == 0 and cur_step > 0:
+ eval_metrics = {}
+ # evaluate
+ for batch in tqdm(
+ eval_data_collator(eval_dataset, eval_batch_size),
+ total=math.ceil(len(eval_dataset) / eval_batch_size),
+ desc="Evaluating ...",
+ position=2,
+ ):
+ labels = batch.pop("labels")
+ predictions = pad_shard_unpad(p_eval_step)(
+ state, batch, min_device_batch=per_device_eval_batch_size
+ )
+ predictions = np.array(predictions)
+ labels[np.array(chain(*batch["attention_mask"])) == 0] = -100
+ preds, refs = get_labels(predictions, labels)
+ metric.add_batch(
+ predictions=preds,
+ references=refs,
+ )
+
+ eval_metrics = compute_metrics()
+
+ if data_args.return_entity_level_metrics:
+ logger.info(f"Step... ({cur_step}/{total_steps} | Validation metrics: {eval_metrics}")
+ else:
+ logger.info(
+ f"Step... ({cur_step}/{total_steps} | Validation f1: {eval_metrics['f1']}, Validation Acc:"
+ f" {eval_metrics['accuracy']})"
+ )
+
+ if has_tensorboard and jax.process_index() == 0:
+ write_eval_metric(summary_writer, eval_metrics, cur_step)
+
+ if (cur_step % training_args.save_steps == 0 and cur_step > 0) or (cur_step == total_steps):
+ # save checkpoint after each epoch and push checkpoint to the hub
+ if jax.process_index() == 0:
+ params = jax.device_get(unreplicate(state.params))
+ model.save_pretrained(training_args.output_dir, params=params)
+ tokenizer.save_pretrained(training_args.output_dir)
+ if training_args.push_to_hub:
+ api.upload_folder(
+ commit_message=f"Saving weights and logs of step {cur_step}",
+ folder_path=training_args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=training_args.hub_token,
+ )
+ epochs.desc = f"Epoch ... {epoch + 1}/{num_epochs}"
+
+ # Eval after training
+ if training_args.do_eval:
+ eval_metrics = {}
+ eval_loader = eval_data_collator(eval_dataset, eval_batch_size)
+ for batch in tqdm(eval_loader, total=len(eval_dataset) // eval_batch_size, desc="Evaluating ...", position=2):
+ labels = batch.pop("labels")
+ predictions = pad_shard_unpad(p_eval_step)(state, batch, min_device_batch=per_device_eval_batch_size)
+ predictions = np.array(predictions)
+ labels[np.array(chain(*batch["attention_mask"])) == 0] = -100
+ preds, refs = get_labels(predictions, labels)
+ metric.add_batch(predictions=preds, references=refs)
+
+ eval_metrics = compute_metrics()
+
+ if jax.process_index() == 0:
+ eval_metrics = {f"eval_{metric_name}": value for metric_name, value in eval_metrics.items()}
+ path = os.path.join(training_args.output_dir, "eval_results.json")
+ with open(path, "w") as f:
+ json.dump(eval_metrics, f, indent=4, sort_keys=True)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/vision/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/vision/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..d865b8a30ce5e0ce4236262cef00e61822f7794f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/vision/README.md
@@ -0,0 +1,70 @@
+
+
+# Image Classification training examples
+
+The following example showcases how to train/fine-tune `ViT` for image-classification using the JAX/Flax backend.
+
+JAX/Flax allows you to trace pure functions and compile them into efficient, fused accelerator code on both GPU and TPU.
+Models written in JAX/Flax are **immutable** and updated in a purely functional
+way which enables simple and efficient model parallelism.
+
+
+In this example we will train/fine-tune the model on the [imagenette](https://github.com/fastai/imagenette) dataset.
+
+## Prepare the dataset
+
+We will use the [imagenette](https://github.com/fastai/imagenette) dataset to train/fine-tune our model. Imagenette is a subset of 10 easily classified classes from Imagenet (tench, English springer, cassette player, chain saw, church, French horn, garbage truck, gas pump, golf ball, parachute).
+
+
+### Download and extract the data.
+
+```bash
+wget https://s3.amazonaws.com/fast-ai-imageclas/imagenette2.tgz
+tar -xvzf imagenette2.tgz
+```
+
+This will create a `imagenette2` dir with two subdirectories `train` and `val` each with multiple subdirectories per class. The training script expects the following directory structure
+
+```bash
+root/dog/xxx.png
+root/dog/xxy.png
+root/dog/[...]/xxz.png
+
+root/cat/123.png
+root/cat/nsdf3.png
+root/cat/[...]/asd932_.png
+```
+
+## Train the model
+
+Next we can run the example script to fine-tune the model:
+
+```bash
+python run_image_classification.py \
+ --output_dir ./vit-base-patch16-imagenette \
+ --model_name_or_path google/vit-base-patch16-224-in21k \
+ --train_dir="imagenette2/train" \
+ --validation_dir="imagenette2/val" \
+ --num_train_epochs 5 \
+ --learning_rate 1e-3 \
+ --per_device_train_batch_size 128 --per_device_eval_batch_size 128 \
+ --overwrite_output_dir \
+ --preprocessing_num_workers 32 \
+ --push_to_hub
+```
+
+This should finish in ~7mins with 99% validation accuracy.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/vision/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/vision/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..8c0e472c86a7f541f2bdb1987baf1902dd063ffb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/vision/requirements.txt
@@ -0,0 +1,8 @@
+jax>=0.2.8
+jaxlib>=0.1.59
+flax>=0.3.5
+optax>=0.0.8
+-f https://download.pytorch.org/whl/torch_stable.html
+torch==2.2.0
+-f https://download.pytorch.org/whl/torch_stable.html
+torchvision==0.12.0+cpu
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/vision/run_image_classification.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/vision/run_image_classification.py
new file mode 100644
index 0000000000000000000000000000000000000000..0228a8797b6edd57a1adb9811beb54b53dd85ab8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/flax/vision/run_image_classification.py
@@ -0,0 +1,591 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Pre-training/Fine-tuning ViT for image classification .
+
+Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
+https://huggingface.co/models?filter=vit
+"""
+
+import logging
+import os
+import sys
+import time
+from dataclasses import asdict, dataclass, field
+from enum import Enum
+from pathlib import Path
+from typing import Callable, Optional
+
+import jax
+import jax.numpy as jnp
+import optax
+
+# for dataset and preprocessing
+import torch
+import torchvision
+import torchvision.transforms as transforms
+from flax import jax_utils
+from flax.jax_utils import pad_shard_unpad, unreplicate
+from flax.training import train_state
+from flax.training.common_utils import get_metrics, onehot, shard, shard_prng_key
+from huggingface_hub import HfApi
+from tqdm import tqdm
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ FLAX_MODEL_FOR_IMAGE_CLASSIFICATION_MAPPING,
+ AutoConfig,
+ FlaxAutoModelForImageClassification,
+ HfArgumentParser,
+ is_tensorboard_available,
+ set_seed,
+)
+from transformers.utils import send_example_telemetry
+
+
+logger = logging.getLogger(__name__)
+
+
+MODEL_CONFIG_CLASSES = list(FLAX_MODEL_FOR_IMAGE_CLASSIFICATION_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+@dataclass
+class TrainingArguments:
+ output_dir: str = field(
+ metadata={"help": "The output directory where the model predictions and checkpoints will be written."},
+ )
+ overwrite_output_dir: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Overwrite the content of the output directory. "
+ "Use this to continue training if output_dir points to a checkpoint directory."
+ )
+ },
+ )
+ do_train: bool = field(default=False, metadata={"help": "Whether to run training."})
+ do_eval: bool = field(default=False, metadata={"help": "Whether to run eval on the dev set."})
+ per_device_train_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for training."}
+ )
+ per_device_eval_batch_size: int = field(
+ default=8, metadata={"help": "Batch size per GPU/TPU core/CPU for evaluation."}
+ )
+ learning_rate: float = field(default=5e-5, metadata={"help": "The initial learning rate for AdamW."})
+ weight_decay: float = field(default=0.0, metadata={"help": "Weight decay for AdamW if we apply some."})
+ adam_beta1: float = field(default=0.9, metadata={"help": "Beta1 for AdamW optimizer"})
+ adam_beta2: float = field(default=0.999, metadata={"help": "Beta2 for AdamW optimizer"})
+ adam_epsilon: float = field(default=1e-8, metadata={"help": "Epsilon for AdamW optimizer."})
+ adafactor: bool = field(default=False, metadata={"help": "Whether or not to replace AdamW by Adafactor."})
+ num_train_epochs: float = field(default=3.0, metadata={"help": "Total number of training epochs to perform."})
+ warmup_steps: int = field(default=0, metadata={"help": "Linear warmup over warmup_steps."})
+ logging_steps: int = field(default=500, metadata={"help": "Log every X updates steps."})
+ save_steps: int = field(default=500, metadata={"help": "Save checkpoint every X updates steps."})
+ eval_steps: int = field(default=None, metadata={"help": "Run an evaluation every X steps."})
+ seed: int = field(default=42, metadata={"help": "Random seed that will be set at the beginning of training."})
+ push_to_hub: bool = field(
+ default=False, metadata={"help": "Whether or not to upload the trained model to the model hub after training."}
+ )
+ hub_model_id: str = field(
+ default=None, metadata={"help": "The name of the repository to keep in sync with the local `output_dir`."}
+ )
+ hub_token: str = field(default=None, metadata={"help": "The token to use to push to the Model Hub."})
+
+ def __post_init__(self):
+ if self.output_dir is not None:
+ self.output_dir = os.path.expanduser(self.output_dir)
+
+ def to_dict(self):
+ """
+ Serializes this instance while replace `Enum` by their values (for JSON serialization support). It obfuscates
+ the token values by removing their value.
+ """
+ d = asdict(self)
+ for k, v in d.items():
+ if isinstance(v, Enum):
+ d[k] = v.value
+ if isinstance(v, list) and len(v) > 0 and isinstance(v[0], Enum):
+ d[k] = [x.value for x in v]
+ if k.endswith("_token"):
+ d[k] = f"<{k.upper()}>"
+ return d
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ model_name_or_path: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
+ )
+ },
+ )
+ model_type: Optional[str] = field(
+ default=None,
+ metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
+ )
+ dtype: Optional[str] = field(
+ default="float32",
+ metadata={
+ "help": (
+ "Floating-point format in which the model weights should be initialized and trained. Choose one of"
+ " `[float32, float16, bfloat16]`."
+ )
+ },
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether or not to allow for custom models defined on the Hub in their own modeling files. This option "
+ "should only be set to `True` for repositories you trust and in which you have read the code, as it will "
+ "execute code present on the Hub on your local machine."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ train_dir: str = field(
+ metadata={"help": "Path to the root training directory which contains one subdirectory per class."}
+ )
+ validation_dir: str = field(
+ metadata={"help": "Path to the root validation directory which contains one subdirectory per class."},
+ )
+ image_size: Optional[int] = field(default=224, metadata={"help": " The size (resolution) of each image."})
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+
+
+class TrainState(train_state.TrainState):
+ dropout_rng: jnp.ndarray
+
+ def replicate(self):
+ return jax_utils.replicate(self).replace(dropout_rng=shard_prng_key(self.dropout_rng))
+
+
+def write_metric(summary_writer, train_metrics, eval_metrics, train_time, step):
+ summary_writer.scalar("train_time", train_time, step)
+
+ train_metrics = get_metrics(train_metrics)
+ for key, vals in train_metrics.items():
+ tag = f"train_{key}"
+ for i, val in enumerate(vals):
+ summary_writer.scalar(tag, val, step - len(vals) + i + 1)
+
+ for metric_name, value in eval_metrics.items():
+ summary_writer.scalar(f"eval_{metric_name}", value, step)
+
+
+def create_learning_rate_fn(
+ train_ds_size: int, train_batch_size: int, num_train_epochs: int, num_warmup_steps: int, learning_rate: float
+) -> Callable[[int], jnp.ndarray]:
+ """Returns a linear warmup, linear_decay learning rate function."""
+ steps_per_epoch = train_ds_size // train_batch_size
+ num_train_steps = steps_per_epoch * num_train_epochs
+ warmup_fn = optax.linear_schedule(init_value=0.0, end_value=learning_rate, transition_steps=num_warmup_steps)
+ decay_fn = optax.linear_schedule(
+ init_value=learning_rate, end_value=0, transition_steps=num_train_steps - num_warmup_steps
+ )
+ schedule_fn = optax.join_schedules(schedules=[warmup_fn, decay_fn], boundaries=[num_warmup_steps])
+ return schedule_fn
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_image_classification", model_args, data_args, framework="flax")
+
+ if (
+ os.path.exists(training_args.output_dir)
+ and os.listdir(training_args.output_dir)
+ and training_args.do_train
+ and not training_args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ # Setup logging, we only want one process per machine to log things on the screen.
+ logger.setLevel(logging.INFO if jax.process_index() == 0 else logging.ERROR)
+ if jax.process_index() == 0:
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ transformers.utils.logging.set_verbosity_error()
+
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # set seed for random transforms and torch dataloaders
+ set_seed(training_args.seed)
+
+ # Handle the repository creation
+ if training_args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = training_args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(training_args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=training_args.hub_token).repo_id
+
+ # Initialize datasets and pre-processing transforms
+ # We use torchvision here for faster pre-processing
+ # Note that here we are using some default pre-processing, for maximum accuracy
+ # one should tune this part and carefully select what transformations to use.
+ normalize = transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
+ train_dataset = torchvision.datasets.ImageFolder(
+ data_args.train_dir,
+ transforms.Compose(
+ [
+ transforms.RandomResizedCrop(data_args.image_size),
+ transforms.RandomHorizontalFlip(),
+ transforms.ToTensor(),
+ normalize,
+ ]
+ ),
+ )
+
+ eval_dataset = torchvision.datasets.ImageFolder(
+ data_args.validation_dir,
+ transforms.Compose(
+ [
+ transforms.Resize(data_args.image_size),
+ transforms.CenterCrop(data_args.image_size),
+ transforms.ToTensor(),
+ normalize,
+ ]
+ ),
+ )
+
+ # Load pretrained model and tokenizer
+ if model_args.config_name:
+ config = AutoConfig.from_pretrained(
+ model_args.config_name,
+ num_labels=len(train_dataset.classes),
+ image_size=data_args.image_size,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ elif model_args.model_name_or_path:
+ config = AutoConfig.from_pretrained(
+ model_args.model_name_or_path,
+ num_labels=len(train_dataset.classes),
+ image_size=data_args.image_size,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ config = CONFIG_MAPPING[model_args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ if model_args.model_name_or_path:
+ model = FlaxAutoModelForImageClassification.from_pretrained(
+ model_args.model_name_or_path,
+ config=config,
+ seed=training_args.seed,
+ dtype=getattr(jnp, model_args.dtype),
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ model = FlaxAutoModelForImageClassification.from_config(
+ config,
+ seed=training_args.seed,
+ dtype=getattr(jnp, model_args.dtype),
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ # Store some constant
+ num_epochs = int(training_args.num_train_epochs)
+ train_batch_size = int(training_args.per_device_train_batch_size) * jax.device_count()
+ per_device_eval_batch_size = int(training_args.per_device_eval_batch_size)
+ eval_batch_size = per_device_eval_batch_size * jax.device_count()
+ steps_per_epoch = len(train_dataset) // train_batch_size
+ total_train_steps = steps_per_epoch * num_epochs
+
+ def collate_fn(examples):
+ pixel_values = torch.stack([example[0] for example in examples])
+ labels = torch.tensor([example[1] for example in examples])
+
+ batch = {"pixel_values": pixel_values, "labels": labels}
+ batch = {k: v.numpy() for k, v in batch.items()}
+
+ return batch
+
+ # Create data loaders
+ train_loader = torch.utils.data.DataLoader(
+ train_dataset,
+ batch_size=train_batch_size,
+ shuffle=True,
+ num_workers=data_args.preprocessing_num_workers,
+ persistent_workers=True,
+ drop_last=True,
+ collate_fn=collate_fn,
+ )
+
+ eval_loader = torch.utils.data.DataLoader(
+ eval_dataset,
+ batch_size=eval_batch_size,
+ shuffle=False,
+ num_workers=data_args.preprocessing_num_workers,
+ persistent_workers=True,
+ drop_last=False,
+ collate_fn=collate_fn,
+ )
+
+ # Enable tensorboard only on the master node
+ has_tensorboard = is_tensorboard_available()
+ if has_tensorboard and jax.process_index() == 0:
+ try:
+ from flax.metrics.tensorboard import SummaryWriter
+
+ summary_writer = SummaryWriter(log_dir=Path(training_args.output_dir))
+ except ImportError as ie:
+ has_tensorboard = False
+ logger.warning(
+ f"Unable to display metrics through TensorBoard because some package are not installed: {ie}"
+ )
+ else:
+ logger.warning(
+ "Unable to display metrics through TensorBoard because the package is not installed: "
+ "Please run pip install tensorboard to enable."
+ )
+
+ # Initialize our training
+ rng = jax.random.PRNGKey(training_args.seed)
+ rng, dropout_rng = jax.random.split(rng)
+
+ # Create learning rate schedule
+ linear_decay_lr_schedule_fn = create_learning_rate_fn(
+ len(train_dataset),
+ train_batch_size,
+ training_args.num_train_epochs,
+ training_args.warmup_steps,
+ training_args.learning_rate,
+ )
+
+ # create adam optimizer
+ adamw = optax.adamw(
+ learning_rate=linear_decay_lr_schedule_fn,
+ b1=training_args.adam_beta1,
+ b2=training_args.adam_beta2,
+ eps=training_args.adam_epsilon,
+ weight_decay=training_args.weight_decay,
+ )
+
+ # Setup train state
+ state = TrainState.create(apply_fn=model.__call__, params=model.params, tx=adamw, dropout_rng=dropout_rng)
+
+ def loss_fn(logits, labels):
+ loss = optax.softmax_cross_entropy(logits, onehot(labels, logits.shape[-1]))
+ return loss.mean()
+
+ # Define gradient update step fn
+ def train_step(state, batch):
+ dropout_rng, new_dropout_rng = jax.random.split(state.dropout_rng)
+
+ def compute_loss(params):
+ labels = batch.pop("labels")
+ logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
+ loss = loss_fn(logits, labels)
+ return loss
+
+ grad_fn = jax.value_and_grad(compute_loss)
+ loss, grad = grad_fn(state.params)
+ grad = jax.lax.pmean(grad, "batch")
+
+ new_state = state.apply_gradients(grads=grad, dropout_rng=new_dropout_rng)
+
+ metrics = {"loss": loss, "learning_rate": linear_decay_lr_schedule_fn(state.step)}
+ metrics = jax.lax.pmean(metrics, axis_name="batch")
+
+ return new_state, metrics
+
+ # Define eval fn
+ def eval_step(params, batch):
+ labels = batch.pop("labels")
+ logits = model(**batch, params=params, train=False)[0]
+ loss = loss_fn(logits, labels)
+
+ # summarize metrics
+ accuracy = (jnp.argmax(logits, axis=-1) == labels).mean()
+ metrics = {"loss": loss, "accuracy": accuracy}
+ metrics = jax.lax.pmean(metrics, axis_name="batch")
+ return metrics
+
+ # Create parallel version of the train and eval step
+ p_train_step = jax.pmap(train_step, "batch", donate_argnums=(0,))
+ p_eval_step = jax.pmap(eval_step, "batch")
+
+ # Replicate the train state on each device
+ state = state.replicate()
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {num_epochs}")
+ logger.info(f" Instantaneous batch size per device = {training_args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel & distributed) = {train_batch_size}")
+ logger.info(f" Total optimization steps = {total_train_steps}")
+
+ train_time = 0
+ epochs = tqdm(range(num_epochs), desc=f"Epoch ... (1/{num_epochs})", position=0)
+ for epoch in epochs:
+ # ======================== Training ================================
+ train_start = time.time()
+
+ # Create sampling rng
+ rng, input_rng = jax.random.split(rng)
+ train_metrics = []
+
+ steps_per_epoch = len(train_dataset) // train_batch_size
+ train_step_progress_bar = tqdm(total=steps_per_epoch, desc="Training...", position=1, leave=False)
+ # train
+ for batch in train_loader:
+ batch = shard(batch)
+ state, train_metric = p_train_step(state, batch)
+ train_metrics.append(train_metric)
+
+ train_step_progress_bar.update(1)
+
+ train_time += time.time() - train_start
+
+ train_metric = unreplicate(train_metric)
+
+ train_step_progress_bar.close()
+ epochs.write(
+ f"Epoch... ({epoch + 1}/{num_epochs} | Loss: {train_metric['loss']}, Learning Rate:"
+ f" {train_metric['learning_rate']})"
+ )
+
+ # ======================== Evaluating ==============================
+ eval_metrics = []
+ eval_steps = len(eval_dataset) // eval_batch_size
+ eval_step_progress_bar = tqdm(total=eval_steps, desc="Evaluating...", position=2, leave=False)
+ for batch in eval_loader:
+ # Model forward
+ metrics = pad_shard_unpad(p_eval_step, static_return=True)(
+ state.params, batch, min_device_batch=per_device_eval_batch_size
+ )
+ eval_metrics.append(metrics)
+
+ eval_step_progress_bar.update(1)
+
+ # normalize eval metrics
+ eval_metrics = get_metrics(eval_metrics)
+ eval_metrics = jax.tree_util.tree_map(jnp.mean, eval_metrics)
+
+ # Print metrics and update progress bar
+ eval_step_progress_bar.close()
+ desc = (
+ f"Epoch... ({epoch + 1}/{num_epochs} | Eval Loss: {round(eval_metrics['loss'].item(), 4)} | "
+ f"Eval Accuracy: {round(eval_metrics['accuracy'].item(), 4)})"
+ )
+ epochs.write(desc)
+ epochs.desc = desc
+
+ # Save metrics
+ if has_tensorboard and jax.process_index() == 0:
+ cur_step = epoch * (len(train_dataset) // train_batch_size)
+ write_metric(summary_writer, train_metrics, eval_metrics, train_time, cur_step)
+
+ # save checkpoint after each epoch and push checkpoint to the hub
+ if jax.process_index() == 0:
+ params = jax.device_get(jax.tree_util.tree_map(lambda x: x[0], state.params))
+ model.save_pretrained(training_args.output_dir, params=params)
+ if training_args.push_to_hub:
+ api.upload_folder(
+ commit_message=f"Saving weights and logs of epoch {epoch}",
+ folder_path=training_args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=training_args.hub_token,
+ )
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..eaf64f624637778d9b07fe3e034c30ca0acb70e9
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/README.md
@@ -0,0 +1,21 @@
+
+
+# Legacy examples
+
+This folder contains examples which are not actively maintained (mostly contributed by the community).
+
+Using these examples together with a recent version of the library usually requires to make small (sometimes big) adaptations to get the scripts working.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/benchmarking/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/benchmarking/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..63cf4e367c3d31f355b2c5282f93a3d7de34e09b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/benchmarking/README.md
@@ -0,0 +1,26 @@
+
+
+# 🤗 Benchmark results
+
+Here, you can find a list of the different benchmark results created by the community.
+
+If you would like to list benchmark results on your favorite models of the [model hub](https://huggingface.co/models) here, please open a Pull Request and add it below.
+
+| Benchmark description | Results | Environment info | Author |
+|:----------|:-------------|:-------------|------:|
+| PyTorch Benchmark on inference for `google-bert/bert-base-cased` |[memory](https://github.com/patrickvonplaten/files_to_link_to/blob/master/bert_benchmark/inference_memory.csv) | [env](https://github.com/patrickvonplaten/files_to_link_to/blob/master/bert_benchmark/env.csv) | [Patrick von Platen](https://github.com/patrickvonplaten) |
+| PyTorch Benchmark on inference for `google-bert/bert-base-cased` |[time](https://github.com/patrickvonplaten/files_to_link_to/blob/master/bert_benchmark/inference_time.csv) | [env](https://github.com/patrickvonplaten/files_to_link_to/blob/master/bert_benchmark/env.csv) | [Patrick von Platen](https://github.com/patrickvonplaten) |
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/benchmarking/plot_csv_file.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/benchmarking/plot_csv_file.py
new file mode 100644
index 0000000000000000000000000000000000000000..aa092f5c047d44c61e1794bb9e873b96467a3d5c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/benchmarking/plot_csv_file.py
@@ -0,0 +1,178 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import csv
+from collections import defaultdict
+from dataclasses import dataclass, field
+from typing import List, Optional
+
+import matplotlib.pyplot as plt
+import numpy as np
+from matplotlib.ticker import ScalarFormatter
+
+from transformers import HfArgumentParser
+
+
+def list_field(default=None, metadata=None):
+ return field(default_factory=lambda: default, metadata=metadata)
+
+
+@dataclass
+class PlotArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ csv_file: str = field(
+ metadata={"help": "The csv file to plot."},
+ )
+ plot_along_batch: bool = field(
+ default=False,
+ metadata={"help": "Whether to plot along batch size or sequence length. Defaults to sequence length."},
+ )
+ is_time: bool = field(
+ default=False,
+ metadata={"help": "Whether the csv file has time results or memory results. Defaults to memory results."},
+ )
+ no_log_scale: bool = field(
+ default=False,
+ metadata={"help": "Disable logarithmic scale when plotting"},
+ )
+ is_train: bool = field(
+ default=False,
+ metadata={
+ "help": "Whether the csv file has training results or inference results. Defaults to inference results."
+ },
+ )
+ figure_png_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "Filename under which the plot will be saved. If unused no plot is saved."},
+ )
+ short_model_names: Optional[List[str]] = list_field(
+ default=None, metadata={"help": "List of model names that are used instead of the ones in the csv file."}
+ )
+
+
+def can_convert_to_int(string):
+ try:
+ int(string)
+ return True
+ except ValueError:
+ return False
+
+
+def can_convert_to_float(string):
+ try:
+ float(string)
+ return True
+ except ValueError:
+ return False
+
+
+class Plot:
+ def __init__(self, args):
+ self.args = args
+ self.result_dict = defaultdict(lambda: {"bsz": [], "seq_len": [], "result": {}})
+
+ with open(self.args.csv_file, newline="") as csv_file:
+ reader = csv.DictReader(csv_file)
+ for row in reader:
+ model_name = row["model"]
+ self.result_dict[model_name]["bsz"].append(int(row["batch_size"]))
+ self.result_dict[model_name]["seq_len"].append(int(row["sequence_length"]))
+ if can_convert_to_int(row["result"]):
+ # value is not None
+ self.result_dict[model_name]["result"][(int(row["batch_size"]), int(row["sequence_length"]))] = (
+ int(row["result"])
+ )
+ elif can_convert_to_float(row["result"]):
+ # value is not None
+ self.result_dict[model_name]["result"][(int(row["batch_size"]), int(row["sequence_length"]))] = (
+ float(row["result"])
+ )
+
+ def plot(self):
+ fig, ax = plt.subplots()
+ title_str = "Time usage" if self.args.is_time else "Memory usage"
+ title_str = title_str + " for training" if self.args.is_train else title_str + " for inference"
+
+ if not self.args.no_log_scale:
+ # set logarithm scales
+ ax.set_xscale("log")
+ ax.set_yscale("log")
+
+ for axis in [ax.xaxis, ax.yaxis]:
+ axis.set_major_formatter(ScalarFormatter())
+
+ for model_name_idx, model_name in enumerate(self.result_dict.keys()):
+ batch_sizes = sorted(set(self.result_dict[model_name]["bsz"]))
+ sequence_lengths = sorted(set(self.result_dict[model_name]["seq_len"]))
+ results = self.result_dict[model_name]["result"]
+
+ (x_axis_array, inner_loop_array) = (
+ (batch_sizes, sequence_lengths) if self.args.plot_along_batch else (sequence_lengths, batch_sizes)
+ )
+
+ label_model_name = (
+ model_name if self.args.short_model_names is None else self.args.short_model_names[model_name_idx]
+ )
+
+ for inner_loop_value in inner_loop_array:
+ if self.args.plot_along_batch:
+ y_axis_array = np.asarray(
+ [results[(x, inner_loop_value)] for x in x_axis_array if (x, inner_loop_value) in results],
+ dtype=int,
+ )
+ else:
+ y_axis_array = np.asarray(
+ [results[(inner_loop_value, x)] for x in x_axis_array if (inner_loop_value, x) in results],
+ dtype=np.float32,
+ )
+
+ (x_axis_label, inner_loop_label) = (
+ ("batch_size", "len") if self.args.plot_along_batch else ("in #tokens", "bsz")
+ )
+
+ x_axis_array = np.asarray(x_axis_array, int)[: len(y_axis_array)]
+ plt.scatter(
+ x_axis_array, y_axis_array, label=f"{label_model_name} - {inner_loop_label}: {inner_loop_value}"
+ )
+ plt.plot(x_axis_array, y_axis_array, "--")
+
+ title_str += f" {label_model_name} vs."
+
+ title_str = title_str[:-4]
+ y_axis_label = "Time in s" if self.args.is_time else "Memory in MB"
+
+ # plot
+ plt.title(title_str)
+ plt.xlabel(x_axis_label)
+ plt.ylabel(y_axis_label)
+ plt.legend()
+
+ if self.args.figure_png_file is not None:
+ plt.savefig(self.args.figure_png_file)
+ else:
+ plt.show()
+
+
+def main():
+ parser = HfArgumentParser(PlotArguments)
+ plot_args = parser.parse_args_into_dataclasses()[0]
+ plot = Plot(args=plot_args)
+ plot.plot()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/benchmarking/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/benchmarking/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..68c56b321909d91ccabb62ebc9a6bca869e9c288
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/benchmarking/requirements.txt
@@ -0,0 +1 @@
+torch >= 1.3
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/benchmarking/run_benchmark.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/benchmarking/run_benchmark.py
new file mode 100644
index 0000000000000000000000000000000000000000..85f266566bfa4e0e2d62ccf8b5732e5846f698c7
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/benchmarking/run_benchmark.py
@@ -0,0 +1,48 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2020 The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Benchmarking the library on inference and training"""
+
+from transformers import HfArgumentParser, PyTorchBenchmark, PyTorchBenchmarkArguments
+
+
+def main():
+ parser = HfArgumentParser(PyTorchBenchmarkArguments)
+ try:
+ benchmark_args = parser.parse_args_into_dataclasses()[0]
+ except ValueError as e:
+ arg_error_msg = "Arg --no_{0} is no longer used, please use --no-{0} instead."
+ begin_error_msg = " ".join(str(e).split(" ")[:-1])
+ full_error_msg = ""
+ depreciated_args = eval(str(e).split(" ")[-1])
+ wrong_args = []
+ for arg in depreciated_args:
+ # arg[2:] removes '--'
+ if arg[2:] in PyTorchBenchmarkArguments.deprecated_args:
+ # arg[5:] removes '--no_'
+ full_error_msg += arg_error_msg.format(arg[5:])
+ else:
+ wrong_args.append(arg)
+ if len(wrong_args) > 0:
+ full_error_msg = full_error_msg + begin_error_msg + str(wrong_args)
+ raise ValueError(full_error_msg)
+
+ benchmark = PyTorchBenchmark(args=benchmark_args)
+ benchmark.run()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/multiple_choice/run_multiple_choice.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/multiple_choice/run_multiple_choice.py
new file mode 100644
index 0000000000000000000000000000000000000000..fece480cad0d4c71b74b08f7b229647166a01f66
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/multiple_choice/run_multiple_choice.py
@@ -0,0 +1,244 @@
+# coding=utf-8
+# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Finetuning the library models for multiple choice (Bert, Roberta, XLNet)."""
+
+import logging
+import os
+from dataclasses import dataclass, field
+from typing import Dict, Optional
+
+import numpy as np
+from utils_multiple_choice import MultipleChoiceDataset, Split, processors
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForMultipleChoice,
+ AutoTokenizer,
+ DataCollatorWithPadding,
+ EvalPrediction,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ set_seed,
+)
+from transformers.trainer_utils import is_main_process
+
+
+logger = logging.getLogger(__name__)
+
+
+def simple_accuracy(preds, labels):
+ return (preds == labels).mean()
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ task_name: str = field(metadata={"help": "The name of the task to train on: " + ", ".join(processors.keys())})
+ data_dir: str = field(metadata={"help": "Should contain the data files for the task."})
+ max_seq_length: int = field(
+ default=128,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ if (
+ os.path.exists(training_args.output_dir)
+ and os.listdir(training_args.output_dir)
+ and training_args.do_train
+ and not training_args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. Use"
+ " --overwrite_output_dir to overcome."
+ )
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO if training_args.local_rank in [-1, 0] else logging.WARN,
+ )
+ logger.warning(
+ "Process rank: %s, device: %s, n_gpu: %s, distributed training: %s, 16-bits training: %s",
+ training_args.local_rank,
+ training_args.device,
+ training_args.n_gpu,
+ bool(training_args.local_rank != -1),
+ training_args.fp16,
+ )
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ if is_main_process(training_args.local_rank):
+ transformers.utils.logging.set_verbosity_info()
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+ logger.info("Training/evaluation parameters %s", training_args)
+
+ # Set seed
+ set_seed(training_args.seed)
+
+ try:
+ processor = processors[data_args.task_name]()
+ label_list = processor.get_labels()
+ num_labels = len(label_list)
+ except KeyError:
+ raise ValueError("Task not found: %s" % (data_args.task_name))
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ num_labels=num_labels,
+ finetuning_task=data_args.task_name,
+ cache_dir=model_args.cache_dir,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ )
+ model = AutoModelForMultipleChoice.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ )
+
+ # Get datasets
+ train_dataset = (
+ MultipleChoiceDataset(
+ data_dir=data_args.data_dir,
+ tokenizer=tokenizer,
+ task=data_args.task_name,
+ max_seq_length=data_args.max_seq_length,
+ overwrite_cache=data_args.overwrite_cache,
+ mode=Split.train,
+ )
+ if training_args.do_train
+ else None
+ )
+ eval_dataset = (
+ MultipleChoiceDataset(
+ data_dir=data_args.data_dir,
+ tokenizer=tokenizer,
+ task=data_args.task_name,
+ max_seq_length=data_args.max_seq_length,
+ overwrite_cache=data_args.overwrite_cache,
+ mode=Split.dev,
+ )
+ if training_args.do_eval
+ else None
+ )
+
+ def compute_metrics(p: EvalPrediction) -> Dict:
+ preds = np.argmax(p.predictions, axis=1)
+ return {"acc": simple_accuracy(preds, p.label_ids)}
+
+ # Data collator
+ data_collator = DataCollatorWithPadding(tokenizer, pad_to_multiple_of=8) if training_args.fp16 else None
+
+ # Initialize our Trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset,
+ eval_dataset=eval_dataset,
+ compute_metrics=compute_metrics,
+ data_collator=data_collator,
+ )
+
+ # Training
+ if training_args.do_train:
+ trainer.train(
+ model_path=model_args.model_name_or_path if os.path.isdir(model_args.model_name_or_path) else None
+ )
+ trainer.save_model()
+ # For convenience, we also re-save the tokenizer to the same directory,
+ # so that you can share your model easily on huggingface.co/models =)
+ if trainer.is_world_master():
+ tokenizer.save_pretrained(training_args.output_dir)
+
+ # Evaluation
+ results = {}
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+
+ result = trainer.evaluate()
+
+ output_eval_file = os.path.join(training_args.output_dir, "eval_results.txt")
+ if trainer.is_world_master():
+ with open(output_eval_file, "w") as writer:
+ logger.info("***** Eval results *****")
+ for key, value in result.items():
+ logger.info(" %s = %s", key, value)
+ writer.write("%s = %s\n" % (key, value))
+
+ results.update(result)
+
+ return results
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/multiple_choice/utils_multiple_choice.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/multiple_choice/utils_multiple_choice.py
new file mode 100644
index 0000000000000000000000000000000000000000..6b7559c49e530d11272a4b85a7f152ec7d45bbcd
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/multiple_choice/utils_multiple_choice.py
@@ -0,0 +1,577 @@
+# coding=utf-8
+# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Multiple choice fine-tuning: utilities to work with multiple choice tasks of reading comprehension"""
+
+import csv
+import glob
+import json
+import logging
+import os
+from dataclasses import dataclass
+from enum import Enum
+from typing import List, Optional
+
+import tqdm
+from filelock import FileLock
+
+from transformers import PreTrainedTokenizer, is_tf_available, is_torch_available
+
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass(frozen=True)
+class InputExample:
+ """
+ A single training/test example for multiple choice
+
+ Args:
+ example_id: Unique id for the example.
+ question: string. The untokenized text of the second sequence (question).
+ contexts: list of str. The untokenized text of the first sequence (context of corresponding question).
+ endings: list of str. multiple choice's options. Its length must be equal to contexts' length.
+ label: (Optional) string. The label of the example. This should be
+ specified for train and dev examples, but not for test examples.
+ """
+
+ example_id: str
+ question: str
+ contexts: List[str]
+ endings: List[str]
+ label: Optional[str]
+
+
+@dataclass(frozen=True)
+class InputFeatures:
+ """
+ A single set of features of data.
+ Property names are the same names as the corresponding inputs to a model.
+ """
+
+ example_id: str
+ input_ids: List[List[int]]
+ attention_mask: Optional[List[List[int]]]
+ token_type_ids: Optional[List[List[int]]]
+ label: Optional[int]
+
+
+class Split(Enum):
+ train = "train"
+ dev = "dev"
+ test = "test"
+
+
+if is_torch_available():
+ import torch
+ from torch.utils.data import Dataset
+
+ class MultipleChoiceDataset(Dataset):
+ """
+ This will be superseded by a framework-agnostic approach
+ soon.
+ """
+
+ features: List[InputFeatures]
+
+ def __init__(
+ self,
+ data_dir: str,
+ tokenizer: PreTrainedTokenizer,
+ task: str,
+ max_seq_length: Optional[int] = None,
+ overwrite_cache=False,
+ mode: Split = Split.train,
+ ):
+ processor = processors[task]()
+
+ cached_features_file = os.path.join(
+ data_dir,
+ "cached_{}_{}_{}_{}".format(
+ mode.value,
+ tokenizer.__class__.__name__,
+ str(max_seq_length),
+ task,
+ ),
+ )
+
+ # Make sure only the first process in distributed training processes the dataset,
+ # and the others will use the cache.
+ lock_path = cached_features_file + ".lock"
+ with FileLock(lock_path):
+ if os.path.exists(cached_features_file) and not overwrite_cache:
+ logger.info(f"Loading features from cached file {cached_features_file}")
+ self.features = torch.load(cached_features_file)
+ else:
+ logger.info(f"Creating features from dataset file at {data_dir}")
+ label_list = processor.get_labels()
+ if mode == Split.dev:
+ examples = processor.get_dev_examples(data_dir)
+ elif mode == Split.test:
+ examples = processor.get_test_examples(data_dir)
+ else:
+ examples = processor.get_train_examples(data_dir)
+ logger.info("Training examples: %s", len(examples))
+ self.features = convert_examples_to_features(
+ examples,
+ label_list,
+ max_seq_length,
+ tokenizer,
+ )
+ logger.info("Saving features into cached file %s", cached_features_file)
+ torch.save(self.features, cached_features_file)
+
+ def __len__(self):
+ return len(self.features)
+
+ def __getitem__(self, i) -> InputFeatures:
+ return self.features[i]
+
+
+if is_tf_available():
+ import tensorflow as tf
+
+ class TFMultipleChoiceDataset:
+ """
+ This will be superseded by a framework-agnostic approach
+ soon.
+ """
+
+ features: List[InputFeatures]
+
+ def __init__(
+ self,
+ data_dir: str,
+ tokenizer: PreTrainedTokenizer,
+ task: str,
+ max_seq_length: Optional[int] = 128,
+ overwrite_cache=False,
+ mode: Split = Split.train,
+ ):
+ processor = processors[task]()
+
+ logger.info(f"Creating features from dataset file at {data_dir}")
+ label_list = processor.get_labels()
+ if mode == Split.dev:
+ examples = processor.get_dev_examples(data_dir)
+ elif mode == Split.test:
+ examples = processor.get_test_examples(data_dir)
+ else:
+ examples = processor.get_train_examples(data_dir)
+ logger.info("Training examples: %s", len(examples))
+
+ self.features = convert_examples_to_features(
+ examples,
+ label_list,
+ max_seq_length,
+ tokenizer,
+ )
+
+ def gen():
+ for ex_index, ex in tqdm.tqdm(enumerate(self.features), desc="convert examples to features"):
+ if ex_index % 10000 == 0:
+ logger.info("Writing example %d of %d" % (ex_index, len(examples)))
+
+ yield (
+ {
+ "example_id": 0,
+ "input_ids": ex.input_ids,
+ "attention_mask": ex.attention_mask,
+ "token_type_ids": ex.token_type_ids,
+ },
+ ex.label,
+ )
+
+ self.dataset = tf.data.Dataset.from_generator(
+ gen,
+ (
+ {
+ "example_id": tf.int32,
+ "input_ids": tf.int32,
+ "attention_mask": tf.int32,
+ "token_type_ids": tf.int32,
+ },
+ tf.int64,
+ ),
+ (
+ {
+ "example_id": tf.TensorShape([]),
+ "input_ids": tf.TensorShape([None, None]),
+ "attention_mask": tf.TensorShape([None, None]),
+ "token_type_ids": tf.TensorShape([None, None]),
+ },
+ tf.TensorShape([]),
+ ),
+ )
+
+ def get_dataset(self):
+ self.dataset = self.dataset.apply(tf.data.experimental.assert_cardinality(len(self.features)))
+
+ return self.dataset
+
+ def __len__(self):
+ return len(self.features)
+
+ def __getitem__(self, i) -> InputFeatures:
+ return self.features[i]
+
+
+class DataProcessor:
+ """Base class for data converters for multiple choice data sets."""
+
+ def get_train_examples(self, data_dir):
+ """Gets a collection of `InputExample`s for the train set."""
+ raise NotImplementedError()
+
+ def get_dev_examples(self, data_dir):
+ """Gets a collection of `InputExample`s for the dev set."""
+ raise NotImplementedError()
+
+ def get_test_examples(self, data_dir):
+ """Gets a collection of `InputExample`s for the test set."""
+ raise NotImplementedError()
+
+ def get_labels(self):
+ """Gets the list of labels for this data set."""
+ raise NotImplementedError()
+
+
+class RaceProcessor(DataProcessor):
+ """Processor for the RACE data set."""
+
+ def get_train_examples(self, data_dir):
+ """See base class."""
+ logger.info("LOOKING AT {} train".format(data_dir))
+ high = os.path.join(data_dir, "train/high")
+ middle = os.path.join(data_dir, "train/middle")
+ high = self._read_txt(high)
+ middle = self._read_txt(middle)
+ return self._create_examples(high + middle, "train")
+
+ def get_dev_examples(self, data_dir):
+ """See base class."""
+ logger.info("LOOKING AT {} dev".format(data_dir))
+ high = os.path.join(data_dir, "dev/high")
+ middle = os.path.join(data_dir, "dev/middle")
+ high = self._read_txt(high)
+ middle = self._read_txt(middle)
+ return self._create_examples(high + middle, "dev")
+
+ def get_test_examples(self, data_dir):
+ """See base class."""
+ logger.info("LOOKING AT {} test".format(data_dir))
+ high = os.path.join(data_dir, "test/high")
+ middle = os.path.join(data_dir, "test/middle")
+ high = self._read_txt(high)
+ middle = self._read_txt(middle)
+ return self._create_examples(high + middle, "test")
+
+ def get_labels(self):
+ """See base class."""
+ return ["0", "1", "2", "3"]
+
+ def _read_txt(self, input_dir):
+ lines = []
+ files = glob.glob(input_dir + "/*txt")
+ for file in tqdm.tqdm(files, desc="read files"):
+ with open(file, "r", encoding="utf-8") as fin:
+ data_raw = json.load(fin)
+ data_raw["race_id"] = file
+ lines.append(data_raw)
+ return lines
+
+ def _create_examples(self, lines, set_type):
+ """Creates examples for the training and dev sets."""
+ examples = []
+ for _, data_raw in enumerate(lines):
+ race_id = "%s-%s" % (set_type, data_raw["race_id"])
+ article = data_raw["article"]
+ for i in range(len(data_raw["answers"])):
+ truth = str(ord(data_raw["answers"][i]) - ord("A"))
+ question = data_raw["questions"][i]
+ options = data_raw["options"][i]
+
+ examples.append(
+ InputExample(
+ example_id=race_id,
+ question=question,
+ contexts=[article, article, article, article], # this is not efficient but convenient
+ endings=[options[0], options[1], options[2], options[3]],
+ label=truth,
+ )
+ )
+ return examples
+
+
+class SynonymProcessor(DataProcessor):
+ """Processor for the Synonym data set."""
+
+ def get_train_examples(self, data_dir):
+ """See base class."""
+ logger.info("LOOKING AT {} train".format(data_dir))
+ return self._create_examples(self._read_csv(os.path.join(data_dir, "mctrain.csv")), "train")
+
+ def get_dev_examples(self, data_dir):
+ """See base class."""
+ logger.info("LOOKING AT {} dev".format(data_dir))
+ return self._create_examples(self._read_csv(os.path.join(data_dir, "mchp.csv")), "dev")
+
+ def get_test_examples(self, data_dir):
+ """See base class."""
+ logger.info("LOOKING AT {} dev".format(data_dir))
+
+ return self._create_examples(self._read_csv(os.path.join(data_dir, "mctest.csv")), "test")
+
+ def get_labels(self):
+ """See base class."""
+ return ["0", "1", "2", "3", "4"]
+
+ def _read_csv(self, input_file):
+ with open(input_file, "r", encoding="utf-8") as f:
+ return list(csv.reader(f))
+
+ def _create_examples(self, lines: List[List[str]], type: str):
+ """Creates examples for the training and dev sets."""
+
+ examples = [
+ InputExample(
+ example_id=line[0],
+ question="", # in the swag dataset, the
+ # common beginning of each
+ # choice is stored in "sent2".
+ contexts=[line[1], line[1], line[1], line[1], line[1]],
+ endings=[line[2], line[3], line[4], line[5], line[6]],
+ label=line[7],
+ )
+ for line in lines # we skip the line with the column names
+ ]
+
+ return examples
+
+
+class SwagProcessor(DataProcessor):
+ """Processor for the SWAG data set."""
+
+ def get_train_examples(self, data_dir):
+ """See base class."""
+ logger.info("LOOKING AT {} train".format(data_dir))
+ return self._create_examples(self._read_csv(os.path.join(data_dir, "train.csv")), "train")
+
+ def get_dev_examples(self, data_dir):
+ """See base class."""
+ logger.info("LOOKING AT {} dev".format(data_dir))
+ return self._create_examples(self._read_csv(os.path.join(data_dir, "val.csv")), "dev")
+
+ def get_test_examples(self, data_dir):
+ """See base class."""
+ logger.info("LOOKING AT {} dev".format(data_dir))
+ raise ValueError(
+ "For swag testing, the input file does not contain a label column. It can not be tested in current code "
+ "setting!"
+ )
+ return self._create_examples(self._read_csv(os.path.join(data_dir, "test.csv")), "test")
+
+ def get_labels(self):
+ """See base class."""
+ return ["0", "1", "2", "3"]
+
+ def _read_csv(self, input_file):
+ with open(input_file, "r", encoding="utf-8") as f:
+ return list(csv.reader(f))
+
+ def _create_examples(self, lines: List[List[str]], type: str):
+ """Creates examples for the training and dev sets."""
+ if type == "train" and lines[0][-1] != "label":
+ raise ValueError("For training, the input file must contain a label column.")
+
+ examples = [
+ InputExample(
+ example_id=line[2],
+ question=line[5], # in the swag dataset, the
+ # common beginning of each
+ # choice is stored in "sent2".
+ contexts=[line[4], line[4], line[4], line[4]],
+ endings=[line[7], line[8], line[9], line[10]],
+ label=line[11],
+ )
+ for line in lines[1:] # we skip the line with the column names
+ ]
+
+ return examples
+
+
+class ArcProcessor(DataProcessor):
+ """Processor for the ARC data set (request from allennlp)."""
+
+ def get_train_examples(self, data_dir):
+ """See base class."""
+ logger.info("LOOKING AT {} train".format(data_dir))
+ return self._create_examples(self._read_json(os.path.join(data_dir, "train.jsonl")), "train")
+
+ def get_dev_examples(self, data_dir):
+ """See base class."""
+ logger.info("LOOKING AT {} dev".format(data_dir))
+ return self._create_examples(self._read_json(os.path.join(data_dir, "dev.jsonl")), "dev")
+
+ def get_test_examples(self, data_dir):
+ logger.info("LOOKING AT {} test".format(data_dir))
+ return self._create_examples(self._read_json(os.path.join(data_dir, "test.jsonl")), "test")
+
+ def get_labels(self):
+ """See base class."""
+ return ["0", "1", "2", "3"]
+
+ def _read_json(self, input_file):
+ with open(input_file, "r", encoding="utf-8") as fin:
+ lines = fin.readlines()
+ return lines
+
+ def _create_examples(self, lines, type):
+ """Creates examples for the training and dev sets."""
+
+ # There are two types of labels. They should be normalized
+ def normalize(truth):
+ if truth in "ABCD":
+ return ord(truth) - ord("A")
+ elif truth in "1234":
+ return int(truth) - 1
+ else:
+ logger.info("truth ERROR! %s", str(truth))
+ return None
+
+ examples = []
+ three_choice = 0
+ four_choice = 0
+ five_choice = 0
+ other_choices = 0
+ # we deleted example which has more than or less than four choices
+ for line in tqdm.tqdm(lines, desc="read arc data"):
+ data_raw = json.loads(line.strip("\n"))
+ if len(data_raw["question"]["choices"]) == 3:
+ three_choice += 1
+ continue
+ elif len(data_raw["question"]["choices"]) == 5:
+ five_choice += 1
+ continue
+ elif len(data_raw["question"]["choices"]) != 4:
+ other_choices += 1
+ continue
+ four_choice += 1
+ truth = str(normalize(data_raw["answerKey"]))
+ assert truth != "None"
+ question_choices = data_raw["question"]
+ question = question_choices["stem"]
+ id = data_raw["id"]
+ options = question_choices["choices"]
+ if len(options) == 4:
+ examples.append(
+ InputExample(
+ example_id=id,
+ question=question,
+ contexts=[
+ options[0]["para"].replace("_", ""),
+ options[1]["para"].replace("_", ""),
+ options[2]["para"].replace("_", ""),
+ options[3]["para"].replace("_", ""),
+ ],
+ endings=[options[0]["text"], options[1]["text"], options[2]["text"], options[3]["text"]],
+ label=truth,
+ )
+ )
+
+ if type == "train":
+ assert len(examples) > 1
+ assert examples[0].label is not None
+ logger.info("len examples: %s}", str(len(examples)))
+ logger.info("Three choices: %s", str(three_choice))
+ logger.info("Five choices: %s", str(five_choice))
+ logger.info("Other choices: %s", str(other_choices))
+ logger.info("four choices: %s", str(four_choice))
+
+ return examples
+
+
+def convert_examples_to_features(
+ examples: List[InputExample],
+ label_list: List[str],
+ max_length: int,
+ tokenizer: PreTrainedTokenizer,
+) -> List[InputFeatures]:
+ """
+ Loads a data file into a list of `InputFeatures`
+ """
+
+ label_map = {label: i for i, label in enumerate(label_list)}
+
+ features = []
+ for ex_index, example in tqdm.tqdm(enumerate(examples), desc="convert examples to features"):
+ if ex_index % 10000 == 0:
+ logger.info("Writing example %d of %d" % (ex_index, len(examples)))
+ choices_inputs = []
+ for ending_idx, (context, ending) in enumerate(zip(example.contexts, example.endings)):
+ text_a = context
+ if example.question.find("_") != -1:
+ # this is for cloze question
+ text_b = example.question.replace("_", ending)
+ else:
+ text_b = example.question + " " + ending
+
+ inputs = tokenizer(
+ text_a,
+ text_b,
+ add_special_tokens=True,
+ max_length=max_length,
+ padding="max_length",
+ truncation=True,
+ return_overflowing_tokens=True,
+ )
+ if "num_truncated_tokens" in inputs and inputs["num_truncated_tokens"] > 0:
+ logger.info(
+ "Attention! you are cropping tokens (swag task is ok). "
+ "If you are training ARC and RACE and you are poping question + options, "
+ "you need to try to use a bigger max seq length!"
+ )
+
+ choices_inputs.append(inputs)
+
+ label = label_map[example.label]
+
+ input_ids = [x["input_ids"] for x in choices_inputs]
+ attention_mask = (
+ [x["attention_mask"] for x in choices_inputs] if "attention_mask" in choices_inputs[0] else None
+ )
+ token_type_ids = (
+ [x["token_type_ids"] for x in choices_inputs] if "token_type_ids" in choices_inputs[0] else None
+ )
+
+ features.append(
+ InputFeatures(
+ example_id=example.example_id,
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ label=label,
+ )
+ )
+
+ for f in features[:2]:
+ logger.info("*** Example ***")
+ logger.info("feature: %s" % f)
+
+ return features
+
+
+processors = {"race": RaceProcessor, "swag": SwagProcessor, "arc": ArcProcessor, "syn": SynonymProcessor}
+MULTIPLE_CHOICE_TASKS_NUM_LABELS = {"race", 4, "swag", 4, "arc", 4, "syn", 5}
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/lightning_base.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/lightning_base.py
new file mode 100644
index 0000000000000000000000000000000000000000..640828bacd3401d94fbe6cd74d816d474719682e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/lightning_base.py
@@ -0,0 +1,393 @@
+import argparse
+import logging
+import os
+from pathlib import Path
+from typing import Any, Dict
+
+import pytorch_lightning as pl
+from pytorch_lightning.utilities import rank_zero_info
+
+from transformers import (
+ AdamW,
+ AutoConfig,
+ AutoModel,
+ AutoModelForPreTraining,
+ AutoModelForQuestionAnswering,
+ AutoModelForSeq2SeqLM,
+ AutoModelForSequenceClassification,
+ AutoModelForTokenClassification,
+ AutoModelWithLMHead,
+ AutoTokenizer,
+ PretrainedConfig,
+ PreTrainedTokenizer,
+)
+from transformers.optimization import (
+ Adafactor,
+ get_cosine_schedule_with_warmup,
+ get_cosine_with_hard_restarts_schedule_with_warmup,
+ get_linear_schedule_with_warmup,
+ get_polynomial_decay_schedule_with_warmup,
+)
+from transformers.utils.versions import require_version
+
+
+logger = logging.getLogger(__name__)
+
+require_version("pytorch_lightning>=1.0.4")
+
+MODEL_MODES = {
+ "base": AutoModel,
+ "sequence-classification": AutoModelForSequenceClassification,
+ "question-answering": AutoModelForQuestionAnswering,
+ "pretraining": AutoModelForPreTraining,
+ "token-classification": AutoModelForTokenClassification,
+ "language-modeling": AutoModelWithLMHead,
+ "summarization": AutoModelForSeq2SeqLM,
+ "translation": AutoModelForSeq2SeqLM,
+}
+
+
+# update this and the import above to support new schedulers from transformers.optimization
+arg_to_scheduler = {
+ "linear": get_linear_schedule_with_warmup,
+ "cosine": get_cosine_schedule_with_warmup,
+ "cosine_w_restarts": get_cosine_with_hard_restarts_schedule_with_warmup,
+ "polynomial": get_polynomial_decay_schedule_with_warmup,
+ # '': get_constant_schedule, # not supported for now
+ # '': get_constant_schedule_with_warmup, # not supported for now
+}
+arg_to_scheduler_choices = sorted(arg_to_scheduler.keys())
+arg_to_scheduler_metavar = "{" + ", ".join(arg_to_scheduler_choices) + "}"
+
+
+class BaseTransformer(pl.LightningModule):
+ def __init__(
+ self,
+ hparams: argparse.Namespace,
+ num_labels=None,
+ mode="base",
+ config=None,
+ tokenizer=None,
+ model=None,
+ **config_kwargs,
+ ):
+ """Initialize a model, tokenizer and config."""
+ super().__init__()
+ # TODO: move to self.save_hyperparameters()
+ # self.save_hyperparameters()
+ # can also expand arguments into trainer signature for easier reading
+
+ self.save_hyperparameters(hparams)
+ self.step_count = 0
+ self.output_dir = Path(self.hparams.output_dir)
+ cache_dir = self.hparams.cache_dir if self.hparams.cache_dir else None
+ if config is None:
+ self.config = AutoConfig.from_pretrained(
+ self.hparams.config_name if self.hparams.config_name else self.hparams.model_name_or_path,
+ **({"num_labels": num_labels} if num_labels is not None else {}),
+ cache_dir=cache_dir,
+ **config_kwargs,
+ )
+ else:
+ self.config: PretrainedConfig = config
+
+ extra_model_params = ("encoder_layerdrop", "decoder_layerdrop", "dropout", "attention_dropout")
+ for p in extra_model_params:
+ if getattr(self.hparams, p, None):
+ assert hasattr(self.config, p), f"model config doesn't have a `{p}` attribute"
+ setattr(self.config, p, getattr(self.hparams, p))
+
+ if tokenizer is None:
+ self.tokenizer = AutoTokenizer.from_pretrained(
+ self.hparams.tokenizer_name if self.hparams.tokenizer_name else self.hparams.model_name_or_path,
+ cache_dir=cache_dir,
+ )
+ else:
+ self.tokenizer: PreTrainedTokenizer = tokenizer
+ self.model_type = MODEL_MODES[mode]
+ if model is None:
+ self.model = self.model_type.from_pretrained(
+ self.hparams.model_name_or_path,
+ from_tf=bool(".ckpt" in self.hparams.model_name_or_path),
+ config=self.config,
+ cache_dir=cache_dir,
+ )
+ else:
+ self.model = model
+
+ def load_hf_checkpoint(self, *args, **kwargs):
+ self.model = self.model_type.from_pretrained(*args, **kwargs)
+
+ def get_lr_scheduler(self):
+ get_schedule_func = arg_to_scheduler[self.hparams.lr_scheduler]
+ scheduler = get_schedule_func(
+ self.opt, num_warmup_steps=self.hparams.warmup_steps, num_training_steps=self.total_steps()
+ )
+ scheduler = {"scheduler": scheduler, "interval": "step", "frequency": 1}
+ return scheduler
+
+ def configure_optimizers(self):
+ """Prepare optimizer and schedule (linear warmup and decay)"""
+ model = self.model
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": self.hparams.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ if self.hparams.adafactor:
+ optimizer = Adafactor(
+ optimizer_grouped_parameters, lr=self.hparams.learning_rate, scale_parameter=False, relative_step=False
+ )
+
+ else:
+ optimizer = AdamW(
+ optimizer_grouped_parameters, lr=self.hparams.learning_rate, eps=self.hparams.adam_epsilon
+ )
+ self.opt = optimizer
+
+ scheduler = self.get_lr_scheduler()
+
+ return [optimizer], [scheduler]
+
+ def test_step(self, batch, batch_nb):
+ return self.validation_step(batch, batch_nb)
+
+ def test_epoch_end(self, outputs):
+ return self.validation_end(outputs)
+
+ def total_steps(self) -> int:
+ """The number of total training steps that will be run. Used for lr scheduler purposes."""
+ num_devices = max(1, self.hparams.gpus) # TODO: consider num_tpu_cores
+ effective_batch_size = self.hparams.train_batch_size * self.hparams.accumulate_grad_batches * num_devices
+ return (self.dataset_size / effective_batch_size) * self.hparams.max_epochs
+
+ def setup(self, mode):
+ if mode == "test":
+ self.dataset_size = len(self.test_dataloader().dataset)
+ else:
+ self.train_loader = self.get_dataloader("train", self.hparams.train_batch_size, shuffle=True)
+ self.dataset_size = len(self.train_dataloader().dataset)
+
+ def get_dataloader(self, type_path: str, batch_size: int, shuffle: bool = False):
+ raise NotImplementedError("You must implement this for your task")
+
+ def train_dataloader(self):
+ return self.train_loader
+
+ def val_dataloader(self):
+ return self.get_dataloader("dev", self.hparams.eval_batch_size, shuffle=False)
+
+ def test_dataloader(self):
+ return self.get_dataloader("test", self.hparams.eval_batch_size, shuffle=False)
+
+ def _feature_file(self, mode):
+ return os.path.join(
+ self.hparams.data_dir,
+ "cached_{}_{}_{}".format(
+ mode,
+ list(filter(None, self.hparams.model_name_or_path.split("/"))).pop(),
+ str(self.hparams.max_seq_length),
+ ),
+ )
+
+ @pl.utilities.rank_zero_only
+ def on_save_checkpoint(self, checkpoint: Dict[str, Any]) -> None:
+ save_path = self.output_dir.joinpath("best_tfmr")
+ self.model.config.save_step = self.step_count
+ self.model.save_pretrained(save_path)
+ self.tokenizer.save_pretrained(save_path)
+
+ @staticmethod
+ def add_model_specific_args(parser, root_dir):
+ parser.add_argument(
+ "--model_name_or_path",
+ default=None,
+ type=str,
+ required=True,
+ help="Path to pretrained model or model identifier from huggingface.co/models",
+ )
+ parser.add_argument(
+ "--config_name", default="", type=str, help="Pretrained config name or path if not the same as model_name"
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ default=None,
+ type=str,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--cache_dir",
+ default="",
+ type=str,
+ help="Where do you want to store the pre-trained models downloaded from huggingface.co",
+ )
+ parser.add_argument(
+ "--encoder_layerdrop",
+ type=float,
+ help="Encoder layer dropout probability (Optional). Goes into model.config",
+ )
+ parser.add_argument(
+ "--decoder_layerdrop",
+ type=float,
+ help="Decoder layer dropout probability (Optional). Goes into model.config",
+ )
+ parser.add_argument(
+ "--dropout",
+ type=float,
+ help="Dropout probability (Optional). Goes into model.config",
+ )
+ parser.add_argument(
+ "--attention_dropout",
+ type=float,
+ help="Attention dropout probability (Optional). Goes into model.config",
+ )
+ parser.add_argument("--learning_rate", default=5e-5, type=float, help="The initial learning rate for Adam.")
+ parser.add_argument(
+ "--lr_scheduler",
+ default="linear",
+ choices=arg_to_scheduler_choices,
+ metavar=arg_to_scheduler_metavar,
+ type=str,
+ help="Learning rate scheduler",
+ )
+ parser.add_argument("--weight_decay", default=0.0, type=float, help="Weight decay if we apply some.")
+ parser.add_argument("--adam_epsilon", default=1e-8, type=float, help="Epsilon for Adam optimizer.")
+ parser.add_argument("--warmup_steps", default=0, type=int, help="Linear warmup over warmup_steps.")
+ parser.add_argument("--num_workers", default=4, type=int, help="kwarg passed to DataLoader")
+ parser.add_argument("--num_train_epochs", dest="max_epochs", default=3, type=int)
+ parser.add_argument("--train_batch_size", default=32, type=int)
+ parser.add_argument("--eval_batch_size", default=32, type=int)
+ parser.add_argument("--adafactor", action="store_true")
+
+
+class LoggingCallback(pl.Callback):
+ def on_batch_end(self, trainer, pl_module):
+ lr_scheduler = trainer.lr_schedulers[0]["scheduler"]
+ lrs = {f"lr_group_{i}": lr for i, lr in enumerate(lr_scheduler.get_lr())}
+ pl_module.logger.log_metrics(lrs)
+
+ def on_validation_end(self, trainer: pl.Trainer, pl_module: pl.LightningModule):
+ rank_zero_info("***** Validation results *****")
+ metrics = trainer.callback_metrics
+ # Log results
+ for key in sorted(metrics):
+ if key not in ["log", "progress_bar"]:
+ rank_zero_info("{} = {}\n".format(key, str(metrics[key])))
+
+ def on_test_end(self, trainer: pl.Trainer, pl_module: pl.LightningModule):
+ rank_zero_info("***** Test results *****")
+ metrics = trainer.callback_metrics
+ # Log and save results to file
+ output_test_results_file = os.path.join(pl_module.hparams.output_dir, "test_results.txt")
+ with open(output_test_results_file, "w") as writer:
+ for key in sorted(metrics):
+ if key not in ["log", "progress_bar"]:
+ rank_zero_info("{} = {}\n".format(key, str(metrics[key])))
+ writer.write("{} = {}\n".format(key, str(metrics[key])))
+
+
+def add_generic_args(parser, root_dir) -> None:
+ # To allow all pl args uncomment the following line
+ # parser = pl.Trainer.add_argparse_args(parser)
+ parser.add_argument(
+ "--output_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The output directory where the model predictions and checkpoints will be written.",
+ )
+ parser.add_argument(
+ "--fp16",
+ action="store_true",
+ help="Whether to use 16-bit (mixed) precision (through NVIDIA apex) instead of 32-bit",
+ )
+
+ parser.add_argument(
+ "--fp16_opt_level",
+ type=str,
+ default="O2",
+ help=(
+ "For fp16: Apex AMP optimization level selected in ['O0', 'O1', 'O2', and 'O3']. "
+ "See details at https://nvidia.github.io/apex/amp.html"
+ ),
+ )
+ parser.add_argument("--n_tpu_cores", dest="tpu_cores", type=int)
+ parser.add_argument("--max_grad_norm", dest="gradient_clip_val", default=1.0, type=float, help="Max gradient norm")
+ parser.add_argument("--do_train", action="store_true", help="Whether to run training.")
+ parser.add_argument("--do_predict", action="store_true", help="Whether to run predictions on the test set.")
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ dest="accumulate_grad_batches",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument("--seed", type=int, default=42, help="random seed for initialization")
+ parser.add_argument(
+ "--data_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The input data dir. Should contain the training files for the CoNLL-2003 NER task.",
+ )
+
+
+def generic_train(
+ model: BaseTransformer,
+ args: argparse.Namespace,
+ early_stopping_callback=None,
+ logger=True, # can pass WandbLogger() here
+ extra_callbacks=[],
+ checkpoint_callback=None,
+ logging_callback=None,
+ **extra_train_kwargs,
+):
+ pl.seed_everything(args.seed)
+
+ # init model
+ odir = Path(model.hparams.output_dir)
+ odir.mkdir(exist_ok=True)
+
+ # add custom checkpoints
+ if checkpoint_callback is None:
+ checkpoint_callback = pl.callbacks.ModelCheckpoint(
+ filepath=args.output_dir, prefix="checkpoint", monitor="val_loss", mode="min", save_top_k=1
+ )
+ if early_stopping_callback:
+ extra_callbacks.append(early_stopping_callback)
+ if logging_callback is None:
+ logging_callback = LoggingCallback()
+
+ train_params = {}
+
+ # TODO: remove with PyTorch 1.6 since pl uses native amp
+ if args.fp16:
+ train_params["precision"] = 16
+ train_params["amp_level"] = args.fp16_opt_level
+
+ if args.gpus > 1:
+ train_params["distributed_backend"] = "ddp"
+
+ train_params["accumulate_grad_batches"] = args.accumulate_grad_batches
+ train_params["accelerator"] = extra_train_kwargs.get("accelerator", None)
+ train_params["profiler"] = extra_train_kwargs.get("profiler", None)
+
+ trainer = pl.Trainer.from_argparse_args(
+ args,
+ weights_summary=None,
+ callbacks=[logging_callback] + extra_callbacks,
+ logger=logger,
+ checkpoint_callback=checkpoint_callback,
+ **train_params,
+ )
+
+ if args.do_train:
+ trainer.fit(model)
+
+ return trainer
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..a6f2d6dce5a9d53013a3c124da6198901486867d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/requirements.txt
@@ -0,0 +1,21 @@
+tensorboard
+scikit-learn
+seqeval
+psutil
+sacrebleu
+rouge-score
+tensorflow_datasets
+matplotlib
+git-python==1.0.3
+faiss-cpu
+streamlit
+elasticsearch
+nltk
+pandas
+datasets >= 1.1.3
+fire
+pytest<8.0.1
+conllu
+sentencepiece != 0.1.92
+protobuf
+ray
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/run_glue.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/run_glue.py
new file mode 100644
index 0000000000000000000000000000000000000000..681f633fcd6d2b403410218805536ee6f002f537
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/run_glue.py
@@ -0,0 +1,201 @@
+import argparse
+import glob
+import logging
+import os
+import time
+from argparse import Namespace
+
+import numpy as np
+import torch
+from lightning_base import BaseTransformer, add_generic_args, generic_train
+from torch.utils.data import DataLoader, TensorDataset
+
+from transformers import glue_compute_metrics as compute_metrics
+from transformers import glue_convert_examples_to_features as convert_examples_to_features
+from transformers import glue_output_modes, glue_tasks_num_labels
+from transformers import glue_processors as processors
+
+
+logger = logging.getLogger(__name__)
+
+
+class GLUETransformer(BaseTransformer):
+ mode = "sequence-classification"
+
+ def __init__(self, hparams):
+ if isinstance(hparams, dict):
+ hparams = Namespace(**hparams)
+ hparams.glue_output_mode = glue_output_modes[hparams.task]
+ num_labels = glue_tasks_num_labels[hparams.task]
+
+ super().__init__(hparams, num_labels, self.mode)
+
+ def forward(self, **inputs):
+ return self.model(**inputs)
+
+ def training_step(self, batch, batch_idx):
+ inputs = {"input_ids": batch[0], "attention_mask": batch[1], "labels": batch[3]}
+
+ if self.config.model_type not in ["distilbert", "bart"]:
+ inputs["token_type_ids"] = batch[2] if self.config.model_type in ["bert", "xlnet", "albert"] else None
+
+ outputs = self(**inputs)
+ loss = outputs[0]
+
+ lr_scheduler = self.trainer.lr_schedulers[0]["scheduler"]
+ tensorboard_logs = {"loss": loss, "rate": lr_scheduler.get_last_lr()[-1]}
+ return {"loss": loss, "log": tensorboard_logs}
+
+ def prepare_data(self):
+ "Called to initialize data. Use the call to construct features"
+ args = self.hparams
+ processor = processors[args.task]()
+ self.labels = processor.get_labels()
+
+ for mode in ["train", "dev"]:
+ cached_features_file = self._feature_file(mode)
+ if os.path.exists(cached_features_file) and not args.overwrite_cache:
+ logger.info("Loading features from cached file %s", cached_features_file)
+ else:
+ logger.info("Creating features from dataset file at %s", args.data_dir)
+ examples = (
+ processor.get_dev_examples(args.data_dir)
+ if mode == "dev"
+ else processor.get_train_examples(args.data_dir)
+ )
+ features = convert_examples_to_features(
+ examples,
+ self.tokenizer,
+ max_length=args.max_seq_length,
+ label_list=self.labels,
+ output_mode=args.glue_output_mode,
+ )
+ logger.info("Saving features into cached file %s", cached_features_file)
+ torch.save(features, cached_features_file)
+
+ def get_dataloader(self, mode: str, batch_size: int, shuffle: bool = False) -> DataLoader:
+ "Load datasets. Called after prepare data."
+
+ # We test on dev set to compare to benchmarks without having to submit to GLUE server
+ mode = "dev" if mode == "test" else mode
+
+ cached_features_file = self._feature_file(mode)
+ logger.info("Loading features from cached file %s", cached_features_file)
+ features = torch.load(cached_features_file)
+ all_input_ids = torch.tensor([f.input_ids for f in features], dtype=torch.long)
+ all_attention_mask = torch.tensor([f.attention_mask for f in features], dtype=torch.long)
+ all_token_type_ids = torch.tensor([f.token_type_ids for f in features], dtype=torch.long)
+ if self.hparams.glue_output_mode == "classification":
+ all_labels = torch.tensor([f.label for f in features], dtype=torch.long)
+ elif self.hparams.glue_output_mode == "regression":
+ all_labels = torch.tensor([f.label for f in features], dtype=torch.float)
+
+ return DataLoader(
+ TensorDataset(all_input_ids, all_attention_mask, all_token_type_ids, all_labels),
+ batch_size=batch_size,
+ shuffle=shuffle,
+ )
+
+ def validation_step(self, batch, batch_idx):
+ inputs = {"input_ids": batch[0], "attention_mask": batch[1], "labels": batch[3]}
+
+ if self.config.model_type not in ["distilbert", "bart"]:
+ inputs["token_type_ids"] = batch[2] if self.config.model_type in ["bert", "xlnet", "albert"] else None
+
+ outputs = self(**inputs)
+ tmp_eval_loss, logits = outputs[:2]
+ preds = logits.detach().cpu().numpy()
+ out_label_ids = inputs["labels"].detach().cpu().numpy()
+
+ return {"val_loss": tmp_eval_loss.detach().cpu(), "pred": preds, "target": out_label_ids}
+
+ def _eval_end(self, outputs) -> tuple:
+ val_loss_mean = torch.stack([x["val_loss"] for x in outputs]).mean().detach().cpu().item()
+ preds = np.concatenate([x["pred"] for x in outputs], axis=0)
+
+ if self.hparams.glue_output_mode == "classification":
+ preds = np.argmax(preds, axis=1)
+ elif self.hparams.glue_output_mode == "regression":
+ preds = np.squeeze(preds)
+
+ out_label_ids = np.concatenate([x["target"] for x in outputs], axis=0)
+ out_label_list = [[] for _ in range(out_label_ids.shape[0])]
+ preds_list = [[] for _ in range(out_label_ids.shape[0])]
+
+ results = {**{"val_loss": val_loss_mean}, **compute_metrics(self.hparams.task, preds, out_label_ids)}
+
+ ret = dict(results.items())
+ ret["log"] = results
+ return ret, preds_list, out_label_list
+
+ def validation_epoch_end(self, outputs: list) -> dict:
+ ret, preds, targets = self._eval_end(outputs)
+ logs = ret["log"]
+ return {"val_loss": logs["val_loss"], "log": logs, "progress_bar": logs}
+
+ def test_epoch_end(self, outputs) -> dict:
+ ret, predictions, targets = self._eval_end(outputs)
+ logs = ret["log"]
+ # `val_loss` is the key returned by `self._eval_end()` but actually refers to `test_loss`
+ return {"avg_test_loss": logs["val_loss"], "log": logs, "progress_bar": logs}
+
+ @staticmethod
+ def add_model_specific_args(parser, root_dir):
+ BaseTransformer.add_model_specific_args(parser, root_dir)
+ parser.add_argument(
+ "--max_seq_length",
+ default=128,
+ type=int,
+ help=(
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ ),
+ )
+
+ parser.add_argument(
+ "--task",
+ default="",
+ type=str,
+ required=True,
+ help="The GLUE task to run",
+ )
+ parser.add_argument(
+ "--gpus",
+ default=0,
+ type=int,
+ help="The number of GPUs allocated for this, it is by default 0 meaning none",
+ )
+
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+
+ return parser
+
+
+def main():
+ parser = argparse.ArgumentParser()
+ add_generic_args(parser, os.getcwd())
+ parser = GLUETransformer.add_model_specific_args(parser, os.getcwd())
+ args = parser.parse_args()
+
+ # If output_dir not provided, a folder will be generated in pwd
+ if args.output_dir is None:
+ args.output_dir = os.path.join(
+ "./results",
+ f"{args.task}_{time.strftime('%Y%m%d_%H%M%S')}",
+ )
+ os.makedirs(args.output_dir)
+
+ model = GLUETransformer(args)
+ trainer = generic_train(model, args)
+
+ # Optionally, predict on dev set and write to output_dir
+ if args.do_predict:
+ checkpoints = sorted(glob.glob(os.path.join(args.output_dir, "checkpoint-epoch=*.ckpt"), recursive=True))
+ model = model.load_from_checkpoint(checkpoints[-1])
+ return trainer.test(model)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/run_glue.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/run_glue.sh
new file mode 100644
index 0000000000000000000000000000000000000000..7cd57306d4e18596b5d7ea70847b5ed5fdcdd7dd
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/run_glue.sh
@@ -0,0 +1,34 @@
+# Install example requirements
+pip install -r ../requirements.txt
+
+# Download glue data
+python3 ../../utils/download_glue_data.py
+
+export TASK=mrpc
+export DATA_DIR=./glue_data/MRPC/
+export MAX_LENGTH=128
+export LEARNING_RATE=2e-5
+export BERT_MODEL=bert-base-cased
+export BATCH_SIZE=32
+export NUM_EPOCHS=3
+export SEED=2
+export OUTPUT_DIR_NAME=mrpc-pl-bert
+export CURRENT_DIR=${PWD}
+export OUTPUT_DIR=${CURRENT_DIR}/${OUTPUT_DIR_NAME}
+
+# Make output directory if it doesn't exist
+mkdir -p $OUTPUT_DIR
+# Add parent directory to python path to access lightning_base.py
+export PYTHONPATH="../":"${PYTHONPATH}"
+
+python3 run_glue.py --gpus 1 --data_dir $DATA_DIR \
+--task $TASK \
+--model_name_or_path $BERT_MODEL \
+--output_dir $OUTPUT_DIR \
+--max_seq_length $MAX_LENGTH \
+--learning_rate $LEARNING_RATE \
+--num_train_epochs $NUM_EPOCHS \
+--train_batch_size $BATCH_SIZE \
+--seed $SEED \
+--do_train \
+--do_predict
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/run_ner.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/run_ner.py
new file mode 100644
index 0000000000000000000000000000000000000000..fc6f812275ea2c92ef81b786d901de0b4b01584c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/run_ner.py
@@ -0,0 +1,216 @@
+import argparse
+import glob
+import logging
+import os
+from argparse import Namespace
+from importlib import import_module
+
+import numpy as np
+import torch
+from lightning_base import BaseTransformer, add_generic_args, generic_train
+from seqeval.metrics import accuracy_score, f1_score, precision_score, recall_score
+from torch.nn import CrossEntropyLoss
+from torch.utils.data import DataLoader, TensorDataset
+from utils_ner import TokenClassificationTask
+
+
+logger = logging.getLogger(__name__)
+
+
+class NERTransformer(BaseTransformer):
+ """
+ A training module for NER. See BaseTransformer for the core options.
+ """
+
+ mode = "token-classification"
+
+ def __init__(self, hparams):
+ if isinstance(hparams, dict):
+ hparams = Namespace(**hparams)
+ module = import_module("tasks")
+ try:
+ token_classification_task_clazz = getattr(module, hparams.task_type)
+ self.token_classification_task: TokenClassificationTask = token_classification_task_clazz()
+ except AttributeError:
+ raise ValueError(
+ f"Task {hparams.task_type} needs to be defined as a TokenClassificationTask subclass in {module}. "
+ f"Available tasks classes are: {TokenClassificationTask.__subclasses__()}"
+ )
+ self.labels = self.token_classification_task.get_labels(hparams.labels)
+ self.pad_token_label_id = CrossEntropyLoss().ignore_index
+ super().__init__(hparams, len(self.labels), self.mode)
+
+ def forward(self, **inputs):
+ return self.model(**inputs)
+
+ def training_step(self, batch, batch_num):
+ "Compute loss and log."
+ inputs = {"input_ids": batch[0], "attention_mask": batch[1], "labels": batch[3]}
+ if self.config.model_type != "distilbert":
+ inputs["token_type_ids"] = (
+ batch[2] if self.config.model_type in ["bert", "xlnet"] else None
+ ) # XLM and RoBERTa don"t use token_type_ids
+
+ outputs = self(**inputs)
+ loss = outputs[0]
+ # tensorboard_logs = {"loss": loss, "rate": self.lr_scheduler.get_last_lr()[-1]}
+ return {"loss": loss}
+
+ def prepare_data(self):
+ "Called to initialize data. Use the call to construct features"
+ args = self.hparams
+ for mode in ["train", "dev", "test"]:
+ cached_features_file = self._feature_file(mode)
+ if os.path.exists(cached_features_file) and not args.overwrite_cache:
+ logger.info("Loading features from cached file %s", cached_features_file)
+ features = torch.load(cached_features_file)
+ else:
+ logger.info("Creating features from dataset file at %s", args.data_dir)
+ examples = self.token_classification_task.read_examples_from_file(args.data_dir, mode)
+ features = self.token_classification_task.convert_examples_to_features(
+ examples,
+ self.labels,
+ args.max_seq_length,
+ self.tokenizer,
+ cls_token_at_end=bool(self.config.model_type in ["xlnet"]),
+ cls_token=self.tokenizer.cls_token,
+ cls_token_segment_id=2 if self.config.model_type in ["xlnet"] else 0,
+ sep_token=self.tokenizer.sep_token,
+ sep_token_extra=False,
+ pad_on_left=bool(self.config.model_type in ["xlnet"]),
+ pad_token=self.tokenizer.pad_token_id,
+ pad_token_segment_id=self.tokenizer.pad_token_type_id,
+ pad_token_label_id=self.pad_token_label_id,
+ )
+ logger.info("Saving features into cached file %s", cached_features_file)
+ torch.save(features, cached_features_file)
+
+ def get_dataloader(self, mode: int, batch_size: int, shuffle: bool = False) -> DataLoader:
+ "Load datasets. Called after prepare data."
+ cached_features_file = self._feature_file(mode)
+ logger.info("Loading features from cached file %s", cached_features_file)
+ features = torch.load(cached_features_file)
+ all_input_ids = torch.tensor([f.input_ids for f in features], dtype=torch.long)
+ all_attention_mask = torch.tensor([f.attention_mask for f in features], dtype=torch.long)
+ if features[0].token_type_ids is not None:
+ all_token_type_ids = torch.tensor([f.token_type_ids for f in features], dtype=torch.long)
+ else:
+ all_token_type_ids = torch.tensor([0 for f in features], dtype=torch.long)
+ # HACK(we will not use this anymore soon)
+ all_label_ids = torch.tensor([f.label_ids for f in features], dtype=torch.long)
+ return DataLoader(
+ TensorDataset(all_input_ids, all_attention_mask, all_token_type_ids, all_label_ids), batch_size=batch_size
+ )
+
+ def validation_step(self, batch, batch_nb):
+ """Compute validation""" ""
+ inputs = {"input_ids": batch[0], "attention_mask": batch[1], "labels": batch[3]}
+ if self.config.model_type != "distilbert":
+ inputs["token_type_ids"] = (
+ batch[2] if self.config.model_type in ["bert", "xlnet"] else None
+ ) # XLM and RoBERTa don"t use token_type_ids
+ outputs = self(**inputs)
+ tmp_eval_loss, logits = outputs[:2]
+ preds = logits.detach().cpu().numpy()
+ out_label_ids = inputs["labels"].detach().cpu().numpy()
+ return {"val_loss": tmp_eval_loss.detach().cpu(), "pred": preds, "target": out_label_ids}
+
+ def _eval_end(self, outputs):
+ "Evaluation called for both Val and Test"
+ val_loss_mean = torch.stack([x["val_loss"] for x in outputs]).mean()
+ preds = np.concatenate([x["pred"] for x in outputs], axis=0)
+ preds = np.argmax(preds, axis=2)
+ out_label_ids = np.concatenate([x["target"] for x in outputs], axis=0)
+
+ label_map = dict(enumerate(self.labels))
+ out_label_list = [[] for _ in range(out_label_ids.shape[0])]
+ preds_list = [[] for _ in range(out_label_ids.shape[0])]
+
+ for i in range(out_label_ids.shape[0]):
+ for j in range(out_label_ids.shape[1]):
+ if out_label_ids[i, j] != self.pad_token_label_id:
+ out_label_list[i].append(label_map[out_label_ids[i][j]])
+ preds_list[i].append(label_map[preds[i][j]])
+
+ results = {
+ "val_loss": val_loss_mean,
+ "accuracy_score": accuracy_score(out_label_list, preds_list),
+ "precision": precision_score(out_label_list, preds_list),
+ "recall": recall_score(out_label_list, preds_list),
+ "f1": f1_score(out_label_list, preds_list),
+ }
+
+ ret = dict(results.items())
+ ret["log"] = results
+ return ret, preds_list, out_label_list
+
+ def validation_epoch_end(self, outputs):
+ # when stable
+ ret, preds, targets = self._eval_end(outputs)
+ logs = ret["log"]
+ return {"val_loss": logs["val_loss"], "log": logs, "progress_bar": logs}
+
+ def test_epoch_end(self, outputs):
+ # updating to test_epoch_end instead of deprecated test_end
+ ret, predictions, targets = self._eval_end(outputs)
+
+ # Converting to the dict required by pl
+ # https://github.com/PyTorchLightning/pytorch-lightning/blob/master/\
+ # pytorch_lightning/trainer/logging.py#L139
+ logs = ret["log"]
+ # `val_loss` is the key returned by `self._eval_end()` but actually refers to `test_loss`
+ return {"avg_test_loss": logs["val_loss"], "log": logs, "progress_bar": logs}
+
+ @staticmethod
+ def add_model_specific_args(parser, root_dir):
+ # Add NER specific options
+ BaseTransformer.add_model_specific_args(parser, root_dir)
+ parser.add_argument(
+ "--task_type", default="NER", type=str, help="Task type to fine tune in training (e.g. NER, POS, etc)"
+ )
+ parser.add_argument(
+ "--max_seq_length",
+ default=128,
+ type=int,
+ help=(
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ ),
+ )
+
+ parser.add_argument(
+ "--labels",
+ default="",
+ type=str,
+ help="Path to a file containing all labels. If not specified, CoNLL-2003 labels are used.",
+ )
+ parser.add_argument(
+ "--gpus",
+ default=0,
+ type=int,
+ help="The number of GPUs allocated for this, it is by default 0 meaning none",
+ )
+
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+
+ return parser
+
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser()
+ add_generic_args(parser, os.getcwd())
+ parser = NERTransformer.add_model_specific_args(parser, os.getcwd())
+ args = parser.parse_args()
+ model = NERTransformer(args)
+ trainer = generic_train(model, args)
+
+ if args.do_predict:
+ # See https://github.com/huggingface/transformers/issues/3159
+ # pl use this default format to create a checkpoint:
+ # https://github.com/PyTorchLightning/pytorch-lightning/blob/master\
+ # /pytorch_lightning/callbacks/model_checkpoint.py#L322
+ checkpoints = sorted(glob.glob(os.path.join(args.output_dir, "checkpoint-epoch=*.ckpt"), recursive=True))
+ model = model.load_from_checkpoint(checkpoints[-1])
+ trainer.test(model)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/run_ner.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/run_ner.sh
new file mode 100644
index 0000000000000000000000000000000000000000..a5b185aa960d09394d7caa12fa5d5dda959cdd61
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/run_ner.sh
@@ -0,0 +1,44 @@
+#!/usr/bin/env bash
+
+# for seqeval metrics import
+pip install -r ../requirements.txt
+
+## The relevant files are currently on a shared Google
+## drive at https://drive.google.com/drive/folders/1kC0I2UGl2ltrluI9NqDjaQJGw5iliw_J
+## Monitor for changes and eventually migrate to use the `datasets` library
+curl -L 'https://drive.google.com/uc?export=download&id=1Jjhbal535VVz2ap4v4r_rN1UEHTdLK5P' \
+| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > train.txt.tmp
+curl -L 'https://drive.google.com/uc?export=download&id=1ZfRcQThdtAR5PPRjIDtrVP7BtXSCUBbm' \
+| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > dev.txt.tmp
+curl -L 'https://drive.google.com/uc?export=download&id=1u9mb7kNJHWQCWyweMDRMuTFoOHOfeBTH' \
+| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > test.txt.tmp
+
+export MAX_LENGTH=128
+export BERT_MODEL=bert-base-multilingual-cased
+python3 scripts/preprocess.py train.txt.tmp $BERT_MODEL $MAX_LENGTH > train.txt
+python3 scripts/preprocess.py dev.txt.tmp $BERT_MODEL $MAX_LENGTH > dev.txt
+python3 scripts/preprocess.py test.txt.tmp $BERT_MODEL $MAX_LENGTH > test.txt
+cat train.txt dev.txt test.txt | cut -d " " -f 2 | grep -v "^$"| sort | uniq > labels.txt
+export BATCH_SIZE=32
+export NUM_EPOCHS=3
+export SEED=1
+
+export OUTPUT_DIR_NAME=germeval-model
+export CURRENT_DIR=${PWD}
+export OUTPUT_DIR=${CURRENT_DIR}/${OUTPUT_DIR_NAME}
+mkdir -p $OUTPUT_DIR
+
+# Add parent directory to python path to access lightning_base.py
+export PYTHONPATH="../":"${PYTHONPATH}"
+
+python3 run_ner.py --data_dir ./ \
+--labels ./labels.txt \
+--model_name_or_path $BERT_MODEL \
+--output_dir $OUTPUT_DIR \
+--max_seq_length $MAX_LENGTH \
+--num_train_epochs $NUM_EPOCHS \
+--train_batch_size $BATCH_SIZE \
+--seed $SEED \
+--gpus 1 \
+--do_train \
+--do_predict
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/run_pos.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/run_pos.sh
new file mode 100644
index 0000000000000000000000000000000000000000..93765366cf3123af5e361c236b46cf36680d90e2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/pytorch-lightning/run_pos.sh
@@ -0,0 +1,39 @@
+#!/usr/bin/env bash
+if ! [ -f ./dev.txt ]; then
+ echo "Download dev dataset...."
+ curl -L -o ./dev.txt 'https://github.com/UniversalDependencies/UD_English-EWT/raw/master/en_ewt-ud-dev.conllu'
+fi
+
+if ! [ -f ./test.txt ]; then
+ echo "Download test dataset...."
+ curl -L -o ./test.txt 'https://github.com/UniversalDependencies/UD_English-EWT/raw/master/en_ewt-ud-test.conllu'
+fi
+
+if ! [ -f ./train.txt ]; then
+ echo "Download train dataset...."
+ curl -L -o ./train.txt 'https://github.com/UniversalDependencies/UD_English-EWT/raw/master/en_ewt-ud-train.conllu'
+fi
+
+export MAX_LENGTH=200
+export BERT_MODEL=bert-base-uncased
+export OUTPUT_DIR=postagger-model
+export BATCH_SIZE=32
+export NUM_EPOCHS=3
+export SAVE_STEPS=750
+export SEED=1
+
+
+# Add parent directory to python path to access lightning_base.py
+export PYTHONPATH="../":"${PYTHONPATH}"
+
+python3 run_ner.py --data_dir ./ \
+--task_type POS \
+--model_name_or_path $BERT_MODEL \
+--output_dir $OUTPUT_DIR \
+--max_seq_length $MAX_LENGTH \
+--num_train_epochs $NUM_EPOCHS \
+--train_batch_size $BATCH_SIZE \
+--seed $SEED \
+--gpus 1 \
+--do_train \
+--do_predict
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/question-answering/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/question-answering/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..339837c94f5d86c79e56f449d2a14b063a3dbf6e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/question-answering/README.md
@@ -0,0 +1,126 @@
+#### Fine-tuning BERT on SQuAD1.0 with relative position embeddings
+
+The following examples show how to fine-tune BERT models with different relative position embeddings. The BERT model
+`google-bert/bert-base-uncased` was pretrained with default absolute position embeddings. We provide the following pretrained
+models which were pre-trained on the same training data (BooksCorpus and English Wikipedia) as in the BERT model
+training, but with different relative position embeddings.
+
+* `zhiheng-huang/bert-base-uncased-embedding-relative-key`, trained from scratch with relative embedding proposed by
+Shaw et al., [Self-Attention with Relative Position Representations](https://arxiv.org/abs/1803.02155)
+* `zhiheng-huang/bert-base-uncased-embedding-relative-key-query`, trained from scratch with relative embedding method 4
+in Huang et al. [Improve Transformer Models with Better Relative Position Embeddings](https://arxiv.org/abs/2009.13658)
+* `zhiheng-huang/bert-large-uncased-whole-word-masking-embedding-relative-key-query`, fine-tuned from model
+`google-bert/bert-large-uncased-whole-word-masking` with 3 additional epochs with relative embedding method 4 in Huang et al.
+[Improve Transformer Models with Better Relative Position Embeddings](https://arxiv.org/abs/2009.13658)
+
+
+##### Base models fine-tuning
+
+```bash
+export CUDA_VISIBLE_DEVICES=0,1,2,3,4,5,6,7
+torchrun --nproc_per_node=8 ./examples/question-answering/run_squad.py \
+ --model_name_or_path zhiheng-huang/bert-base-uncased-embedding-relative-key-query \
+ --dataset_name squad \
+ --do_train \
+ --do_eval \
+ --learning_rate 3e-5 \
+ --num_train_epochs 2 \
+ --max_seq_length 512 \
+ --doc_stride 128 \
+ --output_dir relative_squad \
+ --per_device_eval_batch_size=60 \
+ --per_device_train_batch_size=6
+```
+Training with the above command leads to the following results. It boosts the BERT default from f1 score of 88.52 to 90.54.
+
+```bash
+'exact': 83.6802270577105, 'f1': 90.54772098174814
+```
+
+The change of `max_seq_length` from 512 to 384 in the above command leads to the f1 score of 90.34. Replacing the above
+model `zhiheng-huang/bert-base-uncased-embedding-relative-key-query` with
+`zhiheng-huang/bert-base-uncased-embedding-relative-key` leads to the f1 score of 89.51. The changing of 8 gpus to one
+gpu training leads to the f1 score of 90.71.
+
+##### Large models fine-tuning
+
+```bash
+export CUDA_VISIBLE_DEVICES=0,1,2,3,4,5,6,7
+torchrun --nproc_per_node=8 ./examples/question-answering/run_squad.py \
+ --model_name_or_path zhiheng-huang/bert-large-uncased-whole-word-masking-embedding-relative-key-query \
+ --dataset_name squad \
+ --do_train \
+ --do_eval \
+ --learning_rate 3e-5 \
+ --num_train_epochs 2 \
+ --max_seq_length 512 \
+ --doc_stride 128 \
+ --output_dir relative_squad \
+ --per_gpu_eval_batch_size=6 \
+ --per_gpu_train_batch_size=2 \
+ --gradient_accumulation_steps 3
+```
+Training with the above command leads to the f1 score of 93.52, which is slightly better than the f1 score of 93.15 for
+`google-bert/bert-large-uncased-whole-word-masking`.
+
+#### Distributed training
+
+Here is an example using distributed training on 8 V100 GPUs and Bert Whole Word Masking uncased model to reach a F1 > 93 on SQuAD1.1:
+
+```bash
+torchrun --nproc_per_node=8 ./examples/question-answering/run_squad.py \
+ --model_name_or_path google-bert/bert-large-uncased-whole-word-masking \
+ --dataset_name squad \
+ --do_train \
+ --do_eval \
+ --learning_rate 3e-5 \
+ --num_train_epochs 2 \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir ./examples/models/wwm_uncased_finetuned_squad/ \
+ --per_device_eval_batch_size=3 \
+ --per_device_train_batch_size=3 \
+```
+
+Training with the previously defined hyper-parameters yields the following results:
+
+```bash
+f1 = 93.15
+exact_match = 86.91
+```
+
+This fine-tuned model is available as a checkpoint under the reference
+[`google-bert/bert-large-uncased-whole-word-masking-finetuned-squad`](https://huggingface.co/google-bert/bert-large-uncased-whole-word-masking-finetuned-squad).
+
+## Results
+
+Larger batch size may improve the performance while costing more memory.
+
+##### Results for SQuAD1.0 with the previously defined hyper-parameters:
+
+```python
+{
+"exact": 85.45884578997162,
+"f1": 92.5974600601065,
+"total": 10570,
+"HasAns_exact": 85.45884578997162,
+"HasAns_f1": 92.59746006010651,
+"HasAns_total": 10570
+}
+```
+
+##### Results for SQuAD2.0 with the previously defined hyper-parameters:
+
+```python
+{
+"exact": 80.4177545691906,
+"f1": 84.07154997729623,
+"total": 11873,
+"HasAns_exact": 76.73751686909581,
+"HasAns_f1": 84.05558584352873,
+"HasAns_total": 5928,
+"NoAns_exact": 84.0874684608915,
+"NoAns_f1": 84.0874684608915,
+"NoAns_total": 5945
+}
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/question-answering/run_squad.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/question-answering/run_squad.py
new file mode 100644
index 0000000000000000000000000000000000000000..f5a827c15acac137e19209aaea7a1596bcdcfeaa
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/question-answering/run_squad.py
@@ -0,0 +1,841 @@
+# coding=utf-8
+# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Finetuning the library models for question-answering on SQuAD (DistilBERT, Bert, XLM, XLNet)."""
+
+import argparse
+import glob
+import logging
+import os
+import random
+import timeit
+
+import numpy as np
+import torch
+from torch.utils.data import DataLoader, RandomSampler, SequentialSampler
+from torch.utils.data.distributed import DistributedSampler
+from tqdm import tqdm, trange
+
+import transformers
+from transformers import (
+ MODEL_FOR_QUESTION_ANSWERING_MAPPING,
+ WEIGHTS_NAME,
+ AdamW,
+ AutoConfig,
+ AutoModelForQuestionAnswering,
+ AutoTokenizer,
+ get_linear_schedule_with_warmup,
+ squad_convert_examples_to_features,
+)
+from transformers.data.metrics.squad_metrics import (
+ compute_predictions_log_probs,
+ compute_predictions_logits,
+ squad_evaluate,
+)
+from transformers.data.processors.squad import SquadResult, SquadV1Processor, SquadV2Processor
+from transformers.trainer_utils import is_main_process
+
+
+try:
+ from torch.utils.tensorboard import SummaryWriter
+except ImportError:
+ from tensorboardX import SummaryWriter
+
+
+logger = logging.getLogger(__name__)
+
+MODEL_CONFIG_CLASSES = list(MODEL_FOR_QUESTION_ANSWERING_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+def set_seed(args):
+ random.seed(args.seed)
+ np.random.seed(args.seed)
+ torch.manual_seed(args.seed)
+ if args.n_gpu > 0:
+ torch.cuda.manual_seed_all(args.seed)
+
+
+def to_list(tensor):
+ return tensor.detach().cpu().tolist()
+
+
+def train(args, train_dataset, model, tokenizer):
+ """Train the model"""
+ if args.local_rank in [-1, 0]:
+ tb_writer = SummaryWriter()
+
+ args.train_batch_size = args.per_gpu_train_batch_size * max(1, args.n_gpu)
+ train_sampler = RandomSampler(train_dataset) if args.local_rank == -1 else DistributedSampler(train_dataset)
+ train_dataloader = DataLoader(train_dataset, sampler=train_sampler, batch_size=args.train_batch_size)
+
+ if args.max_steps > 0:
+ t_total = args.max_steps
+ args.num_train_epochs = args.max_steps // (len(train_dataloader) // args.gradient_accumulation_steps) + 1
+ else:
+ t_total = len(train_dataloader) // args.gradient_accumulation_steps * args.num_train_epochs
+
+ # Prepare optimizer and schedule (linear warmup and decay)
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {"params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)], "weight_decay": 0.0},
+ ]
+ optimizer = AdamW(optimizer_grouped_parameters, lr=args.learning_rate, eps=args.adam_epsilon)
+ scheduler = get_linear_schedule_with_warmup(
+ optimizer, num_warmup_steps=args.warmup_steps, num_training_steps=t_total
+ )
+
+ # Check if saved optimizer or scheduler states exist
+ if os.path.isfile(os.path.join(args.model_name_or_path, "optimizer.pt")) and os.path.isfile(
+ os.path.join(args.model_name_or_path, "scheduler.pt")
+ ):
+ # Load in optimizer and scheduler states
+ optimizer.load_state_dict(torch.load(os.path.join(args.model_name_or_path, "optimizer.pt")))
+ scheduler.load_state_dict(torch.load(os.path.join(args.model_name_or_path, "scheduler.pt")))
+
+ if args.fp16:
+ try:
+ from apex import amp
+ except ImportError:
+ raise ImportError("Please install apex from https://www.github.com/nvidia/apex to use fp16 training.")
+
+ model, optimizer = amp.initialize(model, optimizer, opt_level=args.fp16_opt_level)
+
+ # multi-gpu training (should be after apex fp16 initialization)
+ if args.n_gpu > 1:
+ model = torch.nn.DataParallel(model)
+
+ # Distributed training (should be after apex fp16 initialization)
+ if args.local_rank != -1:
+ model = torch.nn.parallel.DistributedDataParallel(
+ model, device_ids=[args.local_rank], output_device=args.local_rank, find_unused_parameters=True
+ )
+
+ # Train!
+ logger.info("***** Running training *****")
+ logger.info(" Num examples = %d", len(train_dataset))
+ logger.info(" Num Epochs = %d", args.num_train_epochs)
+ logger.info(" Instantaneous batch size per GPU = %d", args.per_gpu_train_batch_size)
+ logger.info(
+ " Total train batch size (w. parallel, distributed & accumulation) = %d",
+ args.train_batch_size
+ * args.gradient_accumulation_steps
+ * (torch.distributed.get_world_size() if args.local_rank != -1 else 1),
+ )
+ logger.info(" Gradient Accumulation steps = %d", args.gradient_accumulation_steps)
+ logger.info(" Total optimization steps = %d", t_total)
+
+ global_step = 1
+ epochs_trained = 0
+ steps_trained_in_current_epoch = 0
+ # Check if continuing training from a checkpoint
+ if os.path.exists(args.model_name_or_path):
+ try:
+ # set global_step to global_step of last saved checkpoint from model path
+ checkpoint_suffix = args.model_name_or_path.split("-")[-1].split("/")[0]
+ global_step = int(checkpoint_suffix)
+ epochs_trained = global_step // (len(train_dataloader) // args.gradient_accumulation_steps)
+ steps_trained_in_current_epoch = global_step % (len(train_dataloader) // args.gradient_accumulation_steps)
+
+ logger.info(" Continuing training from checkpoint, will skip to saved global_step")
+ logger.info(" Continuing training from epoch %d", epochs_trained)
+ logger.info(" Continuing training from global step %d", global_step)
+ logger.info(" Will skip the first %d steps in the first epoch", steps_trained_in_current_epoch)
+ except ValueError:
+ logger.info(" Starting fine-tuning.")
+
+ tr_loss, logging_loss = 0.0, 0.0
+ model.zero_grad()
+ train_iterator = trange(
+ epochs_trained, int(args.num_train_epochs), desc="Epoch", disable=args.local_rank not in [-1, 0]
+ )
+ # Added here for reproducibility
+ set_seed(args)
+
+ for _ in train_iterator:
+ epoch_iterator = tqdm(train_dataloader, desc="Iteration", disable=args.local_rank not in [-1, 0])
+ for step, batch in enumerate(epoch_iterator):
+ # Skip past any already trained steps if resuming training
+ if steps_trained_in_current_epoch > 0:
+ steps_trained_in_current_epoch -= 1
+ continue
+
+ model.train()
+ batch = tuple(t.to(args.device) for t in batch)
+
+ inputs = {
+ "input_ids": batch[0],
+ "attention_mask": batch[1],
+ "token_type_ids": batch[2],
+ "start_positions": batch[3],
+ "end_positions": batch[4],
+ }
+
+ if args.model_type in ["xlm", "roberta", "distilbert", "camembert", "bart", "longformer"]:
+ del inputs["token_type_ids"]
+
+ if args.model_type in ["xlnet", "xlm"]:
+ inputs.update({"cls_index": batch[5], "p_mask": batch[6]})
+ if args.version_2_with_negative:
+ inputs.update({"is_impossible": batch[7]})
+ if hasattr(model, "config") and hasattr(model.config, "lang2id"):
+ inputs.update(
+ {"langs": (torch.ones(batch[0].shape, dtype=torch.int64) * args.lang_id).to(args.device)}
+ )
+
+ outputs = model(**inputs)
+ # model outputs are always tuple in transformers (see doc)
+ loss = outputs[0]
+
+ if args.n_gpu > 1:
+ loss = loss.mean() # mean() to average on multi-gpu parallel (not distributed) training
+ if args.gradient_accumulation_steps > 1:
+ loss = loss / args.gradient_accumulation_steps
+
+ if args.fp16:
+ with amp.scale_loss(loss, optimizer) as scaled_loss:
+ scaled_loss.backward()
+ else:
+ loss.backward()
+
+ tr_loss += loss.item()
+ if (step + 1) % args.gradient_accumulation_steps == 0:
+ if args.fp16:
+ torch.nn.utils.clip_grad_norm_(amp.master_params(optimizer), args.max_grad_norm)
+ else:
+ torch.nn.utils.clip_grad_norm_(model.parameters(), args.max_grad_norm)
+
+ optimizer.step()
+ scheduler.step() # Update learning rate schedule
+ model.zero_grad()
+ global_step += 1
+
+ # Log metrics
+ if args.local_rank in [-1, 0] and args.logging_steps > 0 and global_step % args.logging_steps == 0:
+ # Only evaluate when single GPU otherwise metrics may not average well
+ if args.local_rank == -1 and args.evaluate_during_training:
+ results = evaluate(args, model, tokenizer)
+ for key, value in results.items():
+ tb_writer.add_scalar("eval_{}".format(key), value, global_step)
+ tb_writer.add_scalar("lr", scheduler.get_lr()[0], global_step)
+ tb_writer.add_scalar("loss", (tr_loss - logging_loss) / args.logging_steps, global_step)
+ logging_loss = tr_loss
+
+ # Save model checkpoint
+ if args.local_rank in [-1, 0] and args.save_steps > 0 and global_step % args.save_steps == 0:
+ output_dir = os.path.join(args.output_dir, "checkpoint-{}".format(global_step))
+ # Take care of distributed/parallel training
+ model_to_save = model.module if hasattr(model, "module") else model
+ model_to_save.save_pretrained(output_dir)
+ tokenizer.save_pretrained(output_dir)
+
+ torch.save(args, os.path.join(output_dir, "training_args.bin"))
+ logger.info("Saving model checkpoint to %s", output_dir)
+
+ torch.save(optimizer.state_dict(), os.path.join(output_dir, "optimizer.pt"))
+ torch.save(scheduler.state_dict(), os.path.join(output_dir, "scheduler.pt"))
+ logger.info("Saving optimizer and scheduler states to %s", output_dir)
+
+ if args.max_steps > 0 and global_step > args.max_steps:
+ epoch_iterator.close()
+ break
+ if args.max_steps > 0 and global_step > args.max_steps:
+ train_iterator.close()
+ break
+
+ if args.local_rank in [-1, 0]:
+ tb_writer.close()
+
+ return global_step, tr_loss / global_step
+
+
+def evaluate(args, model, tokenizer, prefix=""):
+ dataset, examples, features = load_and_cache_examples(args, tokenizer, evaluate=True, output_examples=True)
+
+ if not os.path.exists(args.output_dir) and args.local_rank in [-1, 0]:
+ os.makedirs(args.output_dir)
+
+ args.eval_batch_size = args.per_gpu_eval_batch_size * max(1, args.n_gpu)
+
+ # Note that DistributedSampler samples randomly
+ eval_sampler = SequentialSampler(dataset)
+ eval_dataloader = DataLoader(dataset, sampler=eval_sampler, batch_size=args.eval_batch_size)
+
+ # multi-gpu evaluate
+ if args.n_gpu > 1 and not isinstance(model, torch.nn.DataParallel):
+ model = torch.nn.DataParallel(model)
+
+ # Eval!
+ logger.info("***** Running evaluation {} *****".format(prefix))
+ logger.info(" Num examples = %d", len(dataset))
+ logger.info(" Batch size = %d", args.eval_batch_size)
+
+ all_results = []
+ start_time = timeit.default_timer()
+
+ for batch in tqdm(eval_dataloader, desc="Evaluating"):
+ model.eval()
+ batch = tuple(t.to(args.device) for t in batch)
+
+ with torch.no_grad():
+ inputs = {
+ "input_ids": batch[0],
+ "attention_mask": batch[1],
+ "token_type_ids": batch[2],
+ }
+
+ if args.model_type in ["xlm", "roberta", "distilbert", "camembert", "bart", "longformer"]:
+ del inputs["token_type_ids"]
+
+ feature_indices = batch[3]
+
+ # XLNet and XLM use more arguments for their predictions
+ if args.model_type in ["xlnet", "xlm"]:
+ inputs.update({"cls_index": batch[4], "p_mask": batch[5]})
+ # for lang_id-sensitive xlm models
+ if hasattr(model, "config") and hasattr(model.config, "lang2id"):
+ inputs.update(
+ {"langs": (torch.ones(batch[0].shape, dtype=torch.int64) * args.lang_id).to(args.device)}
+ )
+ outputs = model(**inputs)
+
+ for i, feature_index in enumerate(feature_indices):
+ eval_feature = features[feature_index.item()]
+ unique_id = int(eval_feature.unique_id)
+
+ output = [to_list(output[i]) for output in outputs.to_tuple()]
+
+ # Some models (XLNet, XLM) use 5 arguments for their predictions, while the other "simpler"
+ # models only use two.
+ if len(output) >= 5:
+ start_logits = output[0]
+ start_top_index = output[1]
+ end_logits = output[2]
+ end_top_index = output[3]
+ cls_logits = output[4]
+
+ result = SquadResult(
+ unique_id,
+ start_logits,
+ end_logits,
+ start_top_index=start_top_index,
+ end_top_index=end_top_index,
+ cls_logits=cls_logits,
+ )
+
+ else:
+ start_logits, end_logits = output
+ result = SquadResult(unique_id, start_logits, end_logits)
+
+ all_results.append(result)
+
+ evalTime = timeit.default_timer() - start_time
+ logger.info(" Evaluation done in total %f secs (%f sec per example)", evalTime, evalTime / len(dataset))
+
+ # Compute predictions
+ output_prediction_file = os.path.join(args.output_dir, "predictions_{}.json".format(prefix))
+ output_nbest_file = os.path.join(args.output_dir, "nbest_predictions_{}.json".format(prefix))
+
+ if args.version_2_with_negative:
+ output_null_log_odds_file = os.path.join(args.output_dir, "null_odds_{}.json".format(prefix))
+ else:
+ output_null_log_odds_file = None
+
+ # XLNet and XLM use a more complex post-processing procedure
+ if args.model_type in ["xlnet", "xlm"]:
+ start_n_top = model.config.start_n_top if hasattr(model, "config") else model.module.config.start_n_top
+ end_n_top = model.config.end_n_top if hasattr(model, "config") else model.module.config.end_n_top
+
+ predictions = compute_predictions_log_probs(
+ examples,
+ features,
+ all_results,
+ args.n_best_size,
+ args.max_answer_length,
+ output_prediction_file,
+ output_nbest_file,
+ output_null_log_odds_file,
+ start_n_top,
+ end_n_top,
+ args.version_2_with_negative,
+ tokenizer,
+ args.verbose_logging,
+ )
+ else:
+ predictions = compute_predictions_logits(
+ examples,
+ features,
+ all_results,
+ args.n_best_size,
+ args.max_answer_length,
+ args.do_lower_case,
+ output_prediction_file,
+ output_nbest_file,
+ output_null_log_odds_file,
+ args.verbose_logging,
+ args.version_2_with_negative,
+ args.null_score_diff_threshold,
+ tokenizer,
+ )
+
+ # Compute the F1 and exact scores.
+ results = squad_evaluate(examples, predictions)
+ return results
+
+
+def load_and_cache_examples(args, tokenizer, evaluate=False, output_examples=False):
+ if args.local_rank not in [-1, 0] and not evaluate:
+ # Make sure only the first process in distributed training process the dataset, and the others will use the cache
+ torch.distributed.barrier()
+
+ # Load data features from cache or dataset file
+ input_dir = args.data_dir if args.data_dir else "."
+ cached_features_file = os.path.join(
+ input_dir,
+ "cached_{}_{}_{}".format(
+ "dev" if evaluate else "train",
+ list(filter(None, args.model_name_or_path.split("/"))).pop(),
+ str(args.max_seq_length),
+ ),
+ )
+
+ # Init features and dataset from cache if it exists
+ if os.path.exists(cached_features_file) and not args.overwrite_cache:
+ logger.info("Loading features from cached file %s", cached_features_file)
+ features_and_dataset = torch.load(cached_features_file)
+ features, dataset, examples = (
+ features_and_dataset["features"],
+ features_and_dataset["dataset"],
+ features_and_dataset["examples"],
+ )
+ else:
+ logger.info("Creating features from dataset file at %s", input_dir)
+
+ if not args.data_dir and ((evaluate and not args.predict_file) or (not evaluate and not args.train_file)):
+ try:
+ import tensorflow_datasets as tfds
+ except ImportError:
+ raise ImportError("If not data_dir is specified, tensorflow_datasets needs to be installed.")
+
+ if args.version_2_with_negative:
+ logger.warning("tensorflow_datasets does not handle version 2 of SQuAD.")
+
+ tfds_examples = tfds.load("squad")
+ examples = SquadV1Processor().get_examples_from_dataset(tfds_examples, evaluate=evaluate)
+ else:
+ processor = SquadV2Processor() if args.version_2_with_negative else SquadV1Processor()
+ if evaluate:
+ examples = processor.get_dev_examples(args.data_dir, filename=args.predict_file)
+ else:
+ examples = processor.get_train_examples(args.data_dir, filename=args.train_file)
+
+ features, dataset = squad_convert_examples_to_features(
+ examples=examples,
+ tokenizer=tokenizer,
+ max_seq_length=args.max_seq_length,
+ doc_stride=args.doc_stride,
+ max_query_length=args.max_query_length,
+ is_training=not evaluate,
+ return_dataset="pt",
+ threads=args.threads,
+ )
+
+ if args.local_rank in [-1, 0]:
+ logger.info("Saving features into cached file %s", cached_features_file)
+ torch.save({"features": features, "dataset": dataset, "examples": examples}, cached_features_file)
+
+ if args.local_rank == 0 and not evaluate:
+ # Make sure only the first process in distributed training process the dataset, and the others will use the cache
+ torch.distributed.barrier()
+
+ if output_examples:
+ return dataset, examples, features
+ return dataset
+
+
+def main():
+ parser = argparse.ArgumentParser()
+
+ # Required parameters
+ parser.add_argument(
+ "--model_type",
+ default=None,
+ type=str,
+ required=True,
+ help="Model type selected in the list: " + ", ".join(MODEL_TYPES),
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ default=None,
+ type=str,
+ required=True,
+ help="Path to pretrained model or model identifier from huggingface.co/models",
+ )
+ parser.add_argument(
+ "--output_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The output directory where the model checkpoints and predictions will be written.",
+ )
+
+ # Other parameters
+ parser.add_argument(
+ "--data_dir",
+ default=None,
+ type=str,
+ help="The input data dir. Should contain the .json files for the task."
+ + "If no data dir or train/predict files are specified, will run with tensorflow_datasets.",
+ )
+ parser.add_argument(
+ "--train_file",
+ default=None,
+ type=str,
+ help="The input training file. If a data dir is specified, will look for the file there"
+ + "If no data dir or train/predict files are specified, will run with tensorflow_datasets.",
+ )
+ parser.add_argument(
+ "--predict_file",
+ default=None,
+ type=str,
+ help="The input evaluation file. If a data dir is specified, will look for the file there"
+ + "If no data dir or train/predict files are specified, will run with tensorflow_datasets.",
+ )
+ parser.add_argument(
+ "--config_name", default="", type=str, help="Pretrained config name or path if not the same as model_name"
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ default="",
+ type=str,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--cache_dir",
+ default="",
+ type=str,
+ help="Where do you want to store the pre-trained models downloaded from huggingface.co",
+ )
+
+ parser.add_argument(
+ "--version_2_with_negative",
+ action="store_true",
+ help="If true, the SQuAD examples contain some that do not have an answer.",
+ )
+ parser.add_argument(
+ "--null_score_diff_threshold",
+ type=float,
+ default=0.0,
+ help="If null_score - best_non_null is greater than the threshold predict null.",
+ )
+
+ parser.add_argument(
+ "--max_seq_length",
+ default=384,
+ type=int,
+ help=(
+ "The maximum total input sequence length after WordPiece tokenization. Sequences "
+ "longer than this will be truncated, and sequences shorter than this will be padded."
+ ),
+ )
+ parser.add_argument(
+ "--doc_stride",
+ default=128,
+ type=int,
+ help="When splitting up a long document into chunks, how much stride to take between chunks.",
+ )
+ parser.add_argument(
+ "--max_query_length",
+ default=64,
+ type=int,
+ help=(
+ "The maximum number of tokens for the question. Questions longer than this will "
+ "be truncated to this length."
+ ),
+ )
+ parser.add_argument("--do_train", action="store_true", help="Whether to run training.")
+ parser.add_argument("--do_eval", action="store_true", help="Whether to run eval on the dev set.")
+ parser.add_argument(
+ "--evaluate_during_training", action="store_true", help="Run evaluation during training at each logging step."
+ )
+ parser.add_argument(
+ "--do_lower_case", action="store_true", help="Set this flag if you are using an uncased model."
+ )
+
+ parser.add_argument("--per_gpu_train_batch_size", default=8, type=int, help="Batch size per GPU/CPU for training.")
+ parser.add_argument(
+ "--per_gpu_eval_batch_size", default=8, type=int, help="Batch size per GPU/CPU for evaluation."
+ )
+ parser.add_argument("--learning_rate", default=5e-5, type=float, help="The initial learning rate for Adam.")
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument("--weight_decay", default=0.0, type=float, help="Weight decay if we apply some.")
+ parser.add_argument("--adam_epsilon", default=1e-8, type=float, help="Epsilon for Adam optimizer.")
+ parser.add_argument("--max_grad_norm", default=1.0, type=float, help="Max gradient norm.")
+ parser.add_argument(
+ "--num_train_epochs", default=3.0, type=float, help="Total number of training epochs to perform."
+ )
+ parser.add_argument(
+ "--max_steps",
+ default=-1,
+ type=int,
+ help="If > 0: set total number of training steps to perform. Override num_train_epochs.",
+ )
+ parser.add_argument("--warmup_steps", default=0, type=int, help="Linear warmup over warmup_steps.")
+ parser.add_argument(
+ "--n_best_size",
+ default=20,
+ type=int,
+ help="The total number of n-best predictions to generate in the nbest_predictions.json output file.",
+ )
+ parser.add_argument(
+ "--max_answer_length",
+ default=30,
+ type=int,
+ help=(
+ "The maximum length of an answer that can be generated. This is needed because the start "
+ "and end predictions are not conditioned on one another."
+ ),
+ )
+ parser.add_argument(
+ "--verbose_logging",
+ action="store_true",
+ help=(
+ "If true, all of the warnings related to data processing will be printed. "
+ "A number of warnings are expected for a normal SQuAD evaluation."
+ ),
+ )
+ parser.add_argument(
+ "--lang_id",
+ default=0,
+ type=int,
+ help=(
+ "language id of input for language-specific xlm models (see"
+ " tokenization_xlm.PRETRAINED_INIT_CONFIGURATION)"
+ ),
+ )
+
+ parser.add_argument("--logging_steps", type=int, default=500, help="Log every X updates steps.")
+ parser.add_argument("--save_steps", type=int, default=500, help="Save checkpoint every X updates steps.")
+ parser.add_argument(
+ "--eval_all_checkpoints",
+ action="store_true",
+ help="Evaluate all checkpoints starting with the same prefix as model_name ending and ending with step number",
+ )
+ parser.add_argument("--no_cuda", action="store_true", help="Whether not to use CUDA when available")
+ parser.add_argument(
+ "--overwrite_output_dir", action="store_true", help="Overwrite the content of the output directory"
+ )
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+ parser.add_argument("--seed", type=int, default=42, help="random seed for initialization")
+
+ parser.add_argument("--local_rank", type=int, default=-1, help="local_rank for distributed training on gpus")
+ parser.add_argument(
+ "--fp16",
+ action="store_true",
+ help="Whether to use 16-bit (mixed) precision (through NVIDIA apex) instead of 32-bit",
+ )
+ parser.add_argument(
+ "--fp16_opt_level",
+ type=str,
+ default="O1",
+ help=(
+ "For fp16: Apex AMP optimization level selected in ['O0', 'O1', 'O2', and 'O3']. "
+ "See details at https://nvidia.github.io/apex/amp.html"
+ ),
+ )
+ parser.add_argument("--server_ip", type=str, default="", help="Can be used for distant debugging.")
+ parser.add_argument("--server_port", type=str, default="", help="Can be used for distant debugging.")
+
+ parser.add_argument("--threads", type=int, default=1, help="multiple threads for converting example to features")
+ args = parser.parse_args()
+
+ if args.doc_stride >= args.max_seq_length - args.max_query_length:
+ logger.warning(
+ "WARNING - You've set a doc stride which may be superior to the document length in some "
+ "examples. This could result in errors when building features from the examples. Please reduce the doc "
+ "stride or increase the maximum length to ensure the features are correctly built."
+ )
+
+ if (
+ os.path.exists(args.output_dir)
+ and os.listdir(args.output_dir)
+ and args.do_train
+ and not args.overwrite_output_dir
+ ):
+ raise ValueError(
+ "Output directory ({}) already exists and is not empty. Use --overwrite_output_dir to overcome.".format(
+ args.output_dir
+ )
+ )
+
+ # Setup distant debugging if needed
+ if args.server_ip and args.server_port:
+ # Distant debugging - see https://code.visualstudio.com/docs/python/debugging#_attach-to-a-local-script
+ import ptvsd
+
+ print("Waiting for debugger attach")
+ ptvsd.enable_attach(address=(args.server_ip, args.server_port), redirect_output=True)
+ ptvsd.wait_for_attach()
+
+ # Setup CUDA, GPU & distributed training
+ if args.local_rank == -1 or args.no_cuda:
+ device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
+ args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
+ else: # Initializes the distributed backend which will take care of synchronizing nodes/GPUs
+ torch.cuda.set_device(args.local_rank)
+ device = torch.device("cuda", args.local_rank)
+ torch.distributed.init_process_group(backend="nccl")
+ args.n_gpu = 1
+ args.device = device
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO if args.local_rank in [-1, 0] else logging.WARN,
+ )
+ logger.warning(
+ "Process rank: %s, device: %s, n_gpu: %s, distributed training: %s, 16-bits training: %s",
+ args.local_rank,
+ device,
+ args.n_gpu,
+ bool(args.local_rank != -1),
+ args.fp16,
+ )
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ if is_main_process(args.local_rank):
+ transformers.utils.logging.set_verbosity_info()
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+ # Set seed
+ set_seed(args)
+
+ # Load pretrained model and tokenizer
+ if args.local_rank not in [-1, 0]:
+ # Make sure only the first process in distributed training will download model & vocab
+ torch.distributed.barrier()
+
+ args.model_type = args.model_type.lower()
+ config = AutoConfig.from_pretrained(
+ args.config_name if args.config_name else args.model_name_or_path,
+ cache_dir=args.cache_dir if args.cache_dir else None,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.tokenizer_name if args.tokenizer_name else args.model_name_or_path,
+ do_lower_case=args.do_lower_case,
+ cache_dir=args.cache_dir if args.cache_dir else None,
+ use_fast=False, # SquadDataset is not compatible with Fast tokenizers which have a smarter overflow handeling
+ )
+ model = AutoModelForQuestionAnswering.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ cache_dir=args.cache_dir if args.cache_dir else None,
+ )
+
+ if args.local_rank == 0:
+ # Make sure only the first process in distributed training will download model & vocab
+ torch.distributed.barrier()
+
+ model.to(args.device)
+
+ logger.info("Training/evaluation parameters %s", args)
+
+ # Before we do anything with models, we want to ensure that we get fp16 execution of torch.einsum if args.fp16 is set.
+ # Otherwise it'll default to "promote" mode, and we'll get fp32 operations. Note that running `--fp16_opt_level="O2"` will
+ # remove the need for this code, but it is still valid.
+ if args.fp16:
+ try:
+ import apex
+
+ apex.amp.register_half_function(torch, "einsum")
+ except ImportError:
+ raise ImportError("Please install apex from https://www.github.com/nvidia/apex to use fp16 training.")
+
+ # Training
+ if args.do_train:
+ train_dataset = load_and_cache_examples(args, tokenizer, evaluate=False, output_examples=False)
+ global_step, tr_loss = train(args, train_dataset, model, tokenizer)
+ logger.info(" global_step = %s, average loss = %s", global_step, tr_loss)
+
+ # Save the trained model and the tokenizer
+ if args.do_train and (args.local_rank == -1 or torch.distributed.get_rank() == 0):
+ logger.info("Saving model checkpoint to %s", args.output_dir)
+ # Save a trained model, configuration and tokenizer using `save_pretrained()`.
+ # They can then be reloaded using `from_pretrained()`
+ # Take care of distributed/parallel training
+ model_to_save = model.module if hasattr(model, "module") else model
+ model_to_save.save_pretrained(args.output_dir)
+ tokenizer.save_pretrained(args.output_dir)
+
+ # Good practice: save your training arguments together with the trained model
+ torch.save(args, os.path.join(args.output_dir, "training_args.bin"))
+
+ # Load a trained model and vocabulary that you have fine-tuned
+ model = AutoModelForQuestionAnswering.from_pretrained(args.output_dir) # , force_download=True)
+
+ # SquadDataset is not compatible with Fast tokenizers which have a smarter overflow handeling
+ # So we use use_fast=False here for now until Fast-tokenizer-compatible-examples are out
+ tokenizer = AutoTokenizer.from_pretrained(args.output_dir, do_lower_case=args.do_lower_case, use_fast=False)
+ model.to(args.device)
+
+ # Evaluation - we can ask to evaluate all the checkpoints (sub-directories) in a directory
+ results = {}
+ if args.do_eval and args.local_rank in [-1, 0]:
+ if args.do_train:
+ logger.info("Loading checkpoints saved during training for evaluation")
+ checkpoints = [args.output_dir]
+ if args.eval_all_checkpoints:
+ checkpoints = [
+ os.path.dirname(c)
+ for c in sorted(glob.glob(args.output_dir + "/**/" + WEIGHTS_NAME, recursive=True))
+ ]
+
+ else:
+ logger.info("Loading checkpoint %s for evaluation", args.model_name_or_path)
+ checkpoints = [args.model_name_or_path]
+
+ logger.info("Evaluate the following checkpoints: %s", checkpoints)
+
+ for checkpoint in checkpoints:
+ # Reload the model
+ global_step = checkpoint.split("-")[-1] if len(checkpoints) > 1 else ""
+ model = AutoModelForQuestionAnswering.from_pretrained(checkpoint) # , force_download=True)
+ model.to(args.device)
+
+ # Evaluate
+ result = evaluate(args, model, tokenizer, prefix=global_step)
+
+ result = {k + ("_{}".format(global_step) if global_step else ""): v for k, v in result.items()}
+ results.update(result)
+
+ logger.info("Results: {}".format(results))
+
+ return results
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/question-answering/run_squad_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/question-answering/run_squad_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..a27cb76295ca940246084e3b134d8656e5d0046f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/question-answering/run_squad_trainer.py
@@ -0,0 +1,186 @@
+# coding=utf-8
+# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fine-tuning the library models for question-answering."""
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from typing import Optional
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForQuestionAnswering,
+ AutoTokenizer,
+ DataCollatorWithPadding,
+ HfArgumentParser,
+ SquadDataset,
+ Trainer,
+ TrainingArguments,
+)
+from transformers import SquadDataTrainingArguments as DataTrainingArguments
+from transformers.trainer_utils import is_main_process
+
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ use_fast: bool = field(default=False, metadata={"help": "Set this flag to use fast tokenization."})
+ # If you want to tweak more attributes on your tokenizer, you should do it in a distinct script,
+ # or just modify its tokenizer_config.json.
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ if (
+ os.path.exists(training_args.output_dir)
+ and os.listdir(training_args.output_dir)
+ and training_args.do_train
+ and not training_args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. Use"
+ " --overwrite_output_dir to overcome."
+ )
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO if training_args.local_rank in [-1, 0] else logging.WARN,
+ )
+ logger.warning(
+ "Process rank: %s, device: %s, n_gpu: %s, distributed training: %s, 16-bits training: %s",
+ training_args.local_rank,
+ training_args.device,
+ training_args.n_gpu,
+ bool(training_args.local_rank != -1),
+ training_args.fp16,
+ )
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ if is_main_process(training_args.local_rank):
+ transformers.utils.logging.set_verbosity_info()
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+ logger.info("Training/evaluation parameters %s", training_args)
+
+ # Prepare Question-Answering task
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=False, # SquadDataset is not compatible with Fast tokenizers which have a smarter overflow handeling
+ )
+ model = AutoModelForQuestionAnswering.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ )
+
+ # Get datasets
+ is_language_sensitive = hasattr(model.config, "lang2id")
+ train_dataset = (
+ SquadDataset(
+ data_args, tokenizer=tokenizer, is_language_sensitive=is_language_sensitive, cache_dir=model_args.cache_dir
+ )
+ if training_args.do_train
+ else None
+ )
+ eval_dataset = (
+ SquadDataset(
+ data_args,
+ tokenizer=tokenizer,
+ mode="dev",
+ is_language_sensitive=is_language_sensitive,
+ cache_dir=model_args.cache_dir,
+ )
+ if training_args.do_eval
+ else None
+ )
+
+ # Data collator
+ data_collator = DataCollatorWithPadding(tokenizer, pad_to_multiple_of=8) if training_args.fp16 else None
+
+ # Initialize our Trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset,
+ eval_dataset=eval_dataset,
+ data_collator=data_collator,
+ )
+
+ # Training
+ if training_args.do_train:
+ trainer.train(
+ model_path=model_args.model_name_or_path if os.path.isdir(model_args.model_name_or_path) else None
+ )
+ trainer.save_model()
+ # For convenience, we also re-save the tokenizer to the same directory,
+ # so that you can share your model easily on huggingface.co/models =)
+ if trainer.is_world_master():
+ tokenizer.save_pretrained(training_args.output_dir)
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_camembert.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_camembert.py
new file mode 100644
index 0000000000000000000000000000000000000000..67e04babe1043e7ca2fc2e2a0a5387837ea8adae
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_camembert.py
@@ -0,0 +1,47 @@
+#!/usr/bin/env python
+import torch
+
+from transformers import CamembertForMaskedLM, CamembertTokenizer
+
+
+def fill_mask(masked_input, model, tokenizer, topk=5):
+ # Adapted from https://github.com/pytorch/fairseq/blob/master/fairseq/models/roberta/hub_interface.py
+ assert masked_input.count("") == 1
+ input_ids = torch.tensor(tokenizer.encode(masked_input, add_special_tokens=True)).unsqueeze(0) # Batch size 1
+ logits = model(input_ids)[0] # The last hidden-state is the first element of the output tuple
+ masked_index = (input_ids.squeeze() == tokenizer.mask_token_id).nonzero().item()
+ logits = logits[0, masked_index, :]
+ prob = logits.softmax(dim=0)
+ values, indices = prob.topk(k=topk, dim=0)
+ topk_predicted_token_bpe = " ".join(
+ [tokenizer.convert_ids_to_tokens(indices[i].item()) for i in range(len(indices))]
+ )
+ masked_token = tokenizer.mask_token
+ topk_filled_outputs = []
+ for index, predicted_token_bpe in enumerate(topk_predicted_token_bpe.split(" ")):
+ predicted_token = predicted_token_bpe.replace("\u2581", " ")
+ if " {0}".format(masked_token) in masked_input:
+ topk_filled_outputs.append(
+ (
+ masked_input.replace(" {0}".format(masked_token), predicted_token),
+ values[index].item(),
+ predicted_token,
+ )
+ )
+ else:
+ topk_filled_outputs.append(
+ (
+ masked_input.replace(masked_token, predicted_token),
+ values[index].item(),
+ predicted_token,
+ )
+ )
+ return topk_filled_outputs
+
+
+tokenizer = CamembertTokenizer.from_pretrained("almanach/camembert-base")
+model = CamembertForMaskedLM.from_pretrained("almanach/camembert-base")
+model.eval()
+
+masked_input = "Le camembert est :)"
+print(fill_mask(masked_input, model, tokenizer, topk=3))
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_chinese_ref.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_chinese_ref.py
new file mode 100644
index 0000000000000000000000000000000000000000..7d73580aa2156618447c841fed74d8a3b3661636
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_chinese_ref.py
@@ -0,0 +1,148 @@
+#!/usr/bin/env python
+import argparse
+import json
+from typing import List
+
+from ltp import LTP
+
+from transformers import BertTokenizer
+
+
+def _is_chinese_char(cp):
+ """Checks whether CP is the codepoint of a CJK character."""
+ # This defines a "chinese character" as anything in the CJK Unicode block:
+ # https://en.wikipedia.org/wiki/CJK_Unified_Ideographs_(Unicode_block)
+ #
+ # Note that the CJK Unicode block is NOT all Japanese and Korean characters,
+ # despite its name. The modern Korean Hangul alphabet is a different block,
+ # as is Japanese Hiragana and Katakana. Those alphabets are used to write
+ # space-separated words, so they are not treated specially and handled
+ # like the all of the other languages.
+ if (
+ (cp >= 0x4E00 and cp <= 0x9FFF)
+ or (cp >= 0x3400 and cp <= 0x4DBF) #
+ or (cp >= 0x20000 and cp <= 0x2A6DF) #
+ or (cp >= 0x2A700 and cp <= 0x2B73F) #
+ or (cp >= 0x2B740 and cp <= 0x2B81F) #
+ or (cp >= 0x2B820 and cp <= 0x2CEAF) #
+ or (cp >= 0xF900 and cp <= 0xFAFF)
+ or (cp >= 0x2F800 and cp <= 0x2FA1F) #
+ ): #
+ return True
+
+ return False
+
+
+def is_chinese(word: str):
+ # word like '180' or '身高' or '神'
+ for char in word:
+ char = ord(char)
+ if not _is_chinese_char(char):
+ return 0
+ return 1
+
+
+def get_chinese_word(tokens: List[str]):
+ word_set = set()
+
+ for token in tokens:
+ chinese_word = len(token) > 1 and is_chinese(token)
+ if chinese_word:
+ word_set.add(token)
+ word_list = list(word_set)
+ return word_list
+
+
+def add_sub_symbol(bert_tokens: List[str], chinese_word_set: set()):
+ if not chinese_word_set:
+ return bert_tokens
+ max_word_len = max([len(w) for w in chinese_word_set])
+
+ bert_word = bert_tokens
+ start, end = 0, len(bert_word)
+ while start < end:
+ single_word = True
+ if is_chinese(bert_word[start]):
+ l = min(end - start, max_word_len)
+ for i in range(l, 1, -1):
+ whole_word = "".join(bert_word[start : start + i])
+ if whole_word in chinese_word_set:
+ for j in range(start + 1, start + i):
+ bert_word[j] = "##" + bert_word[j]
+ start = start + i
+ single_word = False
+ break
+ if single_word:
+ start += 1
+ return bert_word
+
+
+def prepare_ref(lines: List[str], ltp_tokenizer: LTP, bert_tokenizer: BertTokenizer):
+ ltp_res = []
+
+ for i in range(0, len(lines), 100):
+ res = ltp_tokenizer.seg(lines[i : i + 100])[0]
+ res = [get_chinese_word(r) for r in res]
+ ltp_res.extend(res)
+ assert len(ltp_res) == len(lines)
+
+ bert_res = []
+ for i in range(0, len(lines), 100):
+ res = bert_tokenizer(lines[i : i + 100], add_special_tokens=True, truncation=True, max_length=512)
+ bert_res.extend(res["input_ids"])
+ assert len(bert_res) == len(lines)
+
+ ref_ids = []
+ for input_ids, chinese_word in zip(bert_res, ltp_res):
+ input_tokens = []
+ for id in input_ids:
+ token = bert_tokenizer._convert_id_to_token(id)
+ input_tokens.append(token)
+ input_tokens = add_sub_symbol(input_tokens, chinese_word)
+ ref_id = []
+ # We only save pos of chinese subwords start with ##, which mean is part of a whole word.
+ for i, token in enumerate(input_tokens):
+ if token[:2] == "##":
+ clean_token = token[2:]
+ # save chinese tokens' pos
+ if len(clean_token) == 1 and _is_chinese_char(ord(clean_token)):
+ ref_id.append(i)
+ ref_ids.append(ref_id)
+
+ assert len(ref_ids) == len(bert_res)
+
+ return ref_ids
+
+
+def main(args):
+ # For Chinese (Ro)Bert, the best result is from : RoBERTa-wwm-ext (https://github.com/ymcui/Chinese-BERT-wwm)
+ # If we want to fine-tune these model, we have to use same tokenizer : LTP (https://github.com/HIT-SCIR/ltp)
+ with open(args.file_name, "r", encoding="utf-8") as f:
+ data = f.readlines()
+ data = [line.strip() for line in data if len(line) > 0 and not line.isspace()] # avoid delimiter like '\u2029'
+ ltp_tokenizer = LTP(args.ltp) # faster in GPU device
+ bert_tokenizer = BertTokenizer.from_pretrained(args.bert)
+
+ ref_ids = prepare_ref(data, ltp_tokenizer, bert_tokenizer)
+
+ with open(args.save_path, "w", encoding="utf-8") as f:
+ data = [json.dumps(ref) + "\n" for ref in ref_ids]
+ f.writelines(data)
+
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser(description="prepare_chinese_ref")
+ parser.add_argument(
+ "--file_name",
+ type=str,
+ default="./resources/chinese-demo.txt",
+ help="file need process, same as training data in lm",
+ )
+ parser.add_argument(
+ "--ltp", type=str, default="./resources/ltp", help="resources for LTP tokenizer, usually a path"
+ )
+ parser.add_argument("--bert", type=str, default="./resources/robert", help="resources for Bert tokenizer")
+ parser.add_argument("--save_path", type=str, default="./resources/ref.txt", help="path to save res")
+
+ args = parser.parse_args()
+ main(args)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_language_modeling.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_language_modeling.py
new file mode 100644
index 0000000000000000000000000000000000000000..317b2dfb48b56242ad236a9878e712001dff0fcc
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_language_modeling.py
@@ -0,0 +1,374 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for language modeling on a text file (GPT, GPT-2, CTRL, BERT, RoBERTa, XLNet).
+GPT, GPT-2 and CTRL are fine-tuned using a causal language modeling (CLM) loss. BERT and RoBERTa are fine-tuned
+using a masked language modeling (MLM) loss. XLNet is fine-tuned using a permutation language modeling (PLM) loss.
+"""
+
+import logging
+import math
+import os
+from dataclasses import dataclass, field
+from glob import glob
+from typing import Optional
+
+from torch.utils.data import ConcatDataset
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ MODEL_WITH_LM_HEAD_MAPPING,
+ AutoConfig,
+ AutoModelWithLMHead,
+ AutoTokenizer,
+ DataCollatorForLanguageModeling,
+ DataCollatorForPermutationLanguageModeling,
+ DataCollatorForWholeWordMask,
+ HfArgumentParser,
+ LineByLineTextDataset,
+ LineByLineWithRefDataset,
+ PreTrainedTokenizer,
+ TextDataset,
+ Trainer,
+ TrainingArguments,
+ set_seed,
+)
+from transformers.trainer_utils import is_main_process
+
+
+logger = logging.getLogger(__name__)
+
+
+MODEL_CONFIG_CLASSES = list(MODEL_WITH_LM_HEAD_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ model_name_or_path: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The model checkpoint for weights initialization. Leave None if you want to train a model from"
+ " scratch."
+ )
+ },
+ )
+ model_type: Optional[str] = field(
+ default=None,
+ metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ train_data_file: Optional[str] = field(
+ default=None, metadata={"help": "The input training data file (a text file)."}
+ )
+ train_data_files: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The input training data files (multiple files in glob format). "
+ "Very often splitting large files to smaller files can prevent tokenizer going out of memory"
+ )
+ },
+ )
+ eval_data_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ train_ref_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input train ref data file for whole word mask in Chinese."},
+ )
+ eval_ref_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input eval ref data file for whole word mask in Chinese."},
+ )
+ line_by_line: bool = field(
+ default=False,
+ metadata={"help": "Whether distinct lines of text in the dataset are to be handled as distinct sequences."},
+ )
+
+ mlm: bool = field(
+ default=False, metadata={"help": "Train with masked-language modeling loss instead of language modeling."}
+ )
+ whole_word_mask: bool = field(default=False, metadata={"help": "Whether ot not to use whole word mask."})
+ mlm_probability: float = field(
+ default=0.15, metadata={"help": "Ratio of tokens to mask for masked language modeling loss"}
+ )
+ plm_probability: float = field(
+ default=1 / 6,
+ metadata={
+ "help": (
+ "Ratio of length of a span of masked tokens to surrounding context length for permutation language"
+ " modeling."
+ )
+ },
+ )
+ max_span_length: int = field(
+ default=5, metadata={"help": "Maximum length of a span of masked tokens for permutation language modeling."}
+ )
+
+ block_size: int = field(
+ default=-1,
+ metadata={
+ "help": (
+ "Optional input sequence length after tokenization. "
+ "The training dataset will be truncated in block of this size for training."
+ "Default to the model max input length for single sentence inputs (take into account special tokens)."
+ )
+ },
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+
+
+def get_dataset(
+ args: DataTrainingArguments,
+ tokenizer: PreTrainedTokenizer,
+ evaluate: bool = False,
+ cache_dir: Optional[str] = None,
+):
+ def _dataset(file_path, ref_path=None):
+ if args.line_by_line:
+ if ref_path is not None:
+ if not args.whole_word_mask or not args.mlm:
+ raise ValueError("You need to set world whole masking and mlm to True for Chinese Whole Word Mask")
+ return LineByLineWithRefDataset(
+ tokenizer=tokenizer,
+ file_path=file_path,
+ block_size=args.block_size,
+ ref_path=ref_path,
+ )
+
+ return LineByLineTextDataset(tokenizer=tokenizer, file_path=file_path, block_size=args.block_size)
+ else:
+ return TextDataset(
+ tokenizer=tokenizer,
+ file_path=file_path,
+ block_size=args.block_size,
+ overwrite_cache=args.overwrite_cache,
+ cache_dir=cache_dir,
+ )
+
+ if evaluate:
+ return _dataset(args.eval_data_file, args.eval_ref_file)
+ elif args.train_data_files:
+ return ConcatDataset([_dataset(f) for f in glob(args.train_data_files)])
+ else:
+ return _dataset(args.train_data_file, args.train_ref_file)
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ if data_args.eval_data_file is None and training_args.do_eval:
+ raise ValueError(
+ "Cannot do evaluation without an evaluation data file. Either supply a file to --eval_data_file "
+ "or remove the --do_eval argument."
+ )
+ if (
+ os.path.exists(training_args.output_dir)
+ and os.listdir(training_args.output_dir)
+ and training_args.do_train
+ and not training_args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. Use"
+ " --overwrite_output_dir to overcome."
+ )
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO if training_args.local_rank in [-1, 0] else logging.WARN,
+ )
+ logger.warning(
+ "Process rank: %s, device: %s, n_gpu: %s, distributed training: %s, 16-bits training: %s",
+ training_args.local_rank,
+ training_args.device,
+ training_args.n_gpu,
+ bool(training_args.local_rank != -1),
+ training_args.fp16,
+ )
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ if is_main_process(training_args.local_rank):
+ transformers.utils.logging.set_verbosity_info()
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+ logger.info("Training/evaluation parameters %s", training_args)
+
+ # Set seed
+ set_seed(training_args.seed)
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+
+ if model_args.config_name:
+ config = AutoConfig.from_pretrained(model_args.config_name, cache_dir=model_args.cache_dir)
+ elif model_args.model_name_or_path:
+ config = AutoConfig.from_pretrained(model_args.model_name_or_path, cache_dir=model_args.cache_dir)
+ else:
+ config = CONFIG_MAPPING[model_args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ if model_args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(model_args.tokenizer_name, cache_dir=model_args.cache_dir)
+ elif model_args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(model_args.model_name_or_path, cache_dir=model_args.cache_dir)
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported, but you can do it from another"
+ " script, save it,and load it from here, using --tokenizer_name"
+ )
+
+ if model_args.model_name_or_path:
+ model = AutoModelWithLMHead.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = AutoModelWithLMHead.from_config(config)
+
+ model.resize_token_embeddings(len(tokenizer))
+
+ if config.model_type in ["bert", "roberta", "distilbert", "camembert"] and not data_args.mlm:
+ raise ValueError(
+ "BERT and RoBERTa-like models do not have LM heads but masked LM heads. They must be run using the "
+ "--mlm flag (masked language modeling)."
+ )
+
+ if data_args.block_size <= 0:
+ data_args.block_size = tokenizer.max_len
+ # Our input block size will be the max possible for the model
+ else:
+ data_args.block_size = min(data_args.block_size, tokenizer.max_len)
+
+ # Get datasets
+
+ train_dataset = (
+ get_dataset(data_args, tokenizer=tokenizer, cache_dir=model_args.cache_dir) if training_args.do_train else None
+ )
+ eval_dataset = (
+ get_dataset(data_args, tokenizer=tokenizer, evaluate=True, cache_dir=model_args.cache_dir)
+ if training_args.do_eval
+ else None
+ )
+ if config.model_type == "xlnet":
+ data_collator = DataCollatorForPermutationLanguageModeling(
+ tokenizer=tokenizer,
+ plm_probability=data_args.plm_probability,
+ max_span_length=data_args.max_span_length,
+ )
+ else:
+ if data_args.mlm and data_args.whole_word_mask:
+ data_collator = DataCollatorForWholeWordMask(
+ tokenizer=tokenizer, mlm_probability=data_args.mlm_probability
+ )
+ else:
+ data_collator = DataCollatorForLanguageModeling(
+ tokenizer=tokenizer, mlm=data_args.mlm, mlm_probability=data_args.mlm_probability
+ )
+
+ # Initialize our Trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ data_collator=data_collator,
+ train_dataset=train_dataset,
+ eval_dataset=eval_dataset,
+ prediction_loss_only=True,
+ )
+
+ # Training
+ if training_args.do_train:
+ model_path = (
+ model_args.model_name_or_path
+ if model_args.model_name_or_path is not None and os.path.isdir(model_args.model_name_or_path)
+ else None
+ )
+ trainer.train(model_path=model_path)
+ trainer.save_model()
+ # For convenience, we also re-save the tokenizer to the same directory,
+ # so that you can share your model easily on huggingface.co/models =)
+ if trainer.is_world_master():
+ tokenizer.save_pretrained(training_args.output_dir)
+
+ # Evaluation
+ results = {}
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+
+ eval_output = trainer.evaluate()
+
+ perplexity = math.exp(eval_output["eval_loss"])
+ result = {"perplexity": perplexity}
+
+ output_eval_file = os.path.join(training_args.output_dir, "eval_results_lm.txt")
+ if trainer.is_world_master():
+ with open(output_eval_file, "w") as writer:
+ logger.info("***** Eval results *****")
+ for key in sorted(result.keys()):
+ logger.info(" %s = %s", key, str(result[key]))
+ writer.write("%s = %s\n" % (key, str(result[key])))
+
+ results.update(result)
+
+ return results
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_openai_gpt.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_openai_gpt.py
new file mode 100644
index 0000000000000000000000000000000000000000..3831c1bd4401d6906d2769fecfb2741df0dc0e85
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_openai_gpt.py
@@ -0,0 +1,321 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2018 Google AI, Google Brain and Carnegie Mellon University Authors and the HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+""" OpenAI GPT model fine-tuning script.
+ Adapted from https://github.com/huggingface/pytorch-openai-transformer-lm/blob/master/train.py
+ It self adapted from https://github.com/openai/finetune-transformer-lm/blob/master/train.py
+
+ This script with default values fine-tunes and evaluate a pretrained OpenAI GPT on the RocStories dataset:
+ python run_openai_gpt.py \
+ --model_name openai-community/openai-gpt \
+ --do_train \
+ --do_eval \
+ --train_dataset "$ROC_STORIES_DIR/cloze_test_val__spring2016 - cloze_test_ALL_val.csv" \
+ --eval_dataset "$ROC_STORIES_DIR/cloze_test_test__spring2016 - cloze_test_ALL_test.csv" \
+ --output_dir ../log \
+ --train_batch_size 16 \
+"""
+
+import argparse
+import csv
+import logging
+import os
+import random
+
+import numpy as np
+import torch
+from torch.utils.data import DataLoader, RandomSampler, SequentialSampler, TensorDataset
+from tqdm import tqdm, trange
+
+from transformers import (
+ CONFIG_NAME,
+ WEIGHTS_NAME,
+ AdamW,
+ OpenAIGPTDoubleHeadsModel,
+ OpenAIGPTTokenizer,
+ get_linear_schedule_with_warmup,
+)
+
+
+logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s", datefmt="%m/%d/%Y %H:%M:%S", level=logging.INFO
+)
+logger = logging.getLogger(__name__)
+
+
+def accuracy(out, labels):
+ outputs = np.argmax(out, axis=1)
+ return np.sum(outputs == labels)
+
+
+def load_rocstories_dataset(dataset_path):
+ """Output a list of tuples(story, 1st continuation, 2nd continuation, label)"""
+ with open(dataset_path, encoding="utf_8") as f:
+ f = csv.reader(f)
+ output = []
+ next(f) # skip the first line
+ for line in tqdm(f):
+ output.append((" ".join(line[1:5]), line[5], line[6], int(line[-1]) - 1))
+ return output
+
+
+def pre_process_datasets(encoded_datasets, input_len, cap_length, start_token, delimiter_token, clf_token):
+ """Pre-process datasets containing lists of tuples(story, 1st continuation, 2nd continuation, label)
+
+ To Transformer inputs of shape (n_batch, n_alternative, length) comprising for each batch, continuation:
+ input_ids[batch, alternative, :] = [start_token] + story[:cap_length] + [delimiter_token] + cont1[:cap_length] + [clf_token]
+ """
+ tensor_datasets = []
+ for dataset in encoded_datasets:
+ n_batch = len(dataset)
+ input_ids = np.zeros((n_batch, 2, input_len), dtype=np.int64)
+ mc_token_ids = np.zeros((n_batch, 2), dtype=np.int64)
+ lm_labels = np.full((n_batch, 2, input_len), fill_value=-100, dtype=np.int64)
+ mc_labels = np.zeros((n_batch,), dtype=np.int64)
+ for (
+ i,
+ (story, cont1, cont2, mc_label),
+ ) in enumerate(dataset):
+ with_cont1 = [start_token] + story[:cap_length] + [delimiter_token] + cont1[:cap_length] + [clf_token]
+ with_cont2 = [start_token] + story[:cap_length] + [delimiter_token] + cont2[:cap_length] + [clf_token]
+ input_ids[i, 0, : len(with_cont1)] = with_cont1
+ input_ids[i, 1, : len(with_cont2)] = with_cont2
+ mc_token_ids[i, 0] = len(with_cont1) - 1
+ mc_token_ids[i, 1] = len(with_cont2) - 1
+ lm_labels[i, 0, : len(with_cont1)] = with_cont1
+ lm_labels[i, 1, : len(with_cont2)] = with_cont2
+ mc_labels[i] = mc_label
+ all_inputs = (input_ids, mc_token_ids, lm_labels, mc_labels)
+ tensor_datasets.append(tuple(torch.tensor(t) for t in all_inputs))
+ return tensor_datasets
+
+
+def main():
+ parser = argparse.ArgumentParser()
+ parser.add_argument("--model_name", type=str, default="openai-community/openai-gpt", help="pretrained model name")
+ parser.add_argument("--do_train", action="store_true", help="Whether to run training.")
+ parser.add_argument("--do_eval", action="store_true", help="Whether to run eval on the dev set.")
+ parser.add_argument(
+ "--output_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The output directory where the model predictions and checkpoints will be written.",
+ )
+ parser.add_argument("--train_dataset", type=str, default="")
+ parser.add_argument("--eval_dataset", type=str, default="")
+ parser.add_argument("--seed", type=int, default=42)
+ parser.add_argument("--num_train_epochs", type=int, default=3)
+ parser.add_argument("--train_batch_size", type=int, default=8)
+ parser.add_argument("--eval_batch_size", type=int, default=16)
+ parser.add_argument("--adam_epsilon", default=1e-8, type=float, help="Epsilon for Adam optimizer.")
+ parser.add_argument("--max_grad_norm", type=int, default=1)
+ parser.add_argument(
+ "--max_steps",
+ default=-1,
+ type=int,
+ help=(
+ "If > 0: set total number of training steps to perform. Override num_train_epochs."
+ ),
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument("--learning_rate", type=float, default=6.25e-5)
+ parser.add_argument("--warmup_steps", default=0, type=int, help="Linear warmup over warmup_steps.")
+ parser.add_argument("--lr_schedule", type=str, default="warmup_linear")
+ parser.add_argument("--weight_decay", type=float, default=0.01)
+ parser.add_argument("--lm_coef", type=float, default=0.9)
+ parser.add_argument("--n_valid", type=int, default=374)
+
+ parser.add_argument("--server_ip", type=str, default="", help="Can be used for distant debugging.")
+ parser.add_argument("--server_port", type=str, default="", help="Can be used for distant debugging.")
+ args = parser.parse_args()
+ print(args)
+
+ if args.server_ip and args.server_port:
+ # Distant debugging - see https://code.visualstudio.com/docs/python/debugging#_attach-to-a-local-script
+ import ptvsd
+
+ print("Waiting for debugger attach")
+ ptvsd.enable_attach(address=(args.server_ip, args.server_port), redirect_output=True)
+ ptvsd.wait_for_attach()
+
+ random.seed(args.seed)
+ np.random.seed(args.seed)
+ torch.manual_seed(args.seed)
+ torch.cuda.manual_seed_all(args.seed)
+
+ device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
+ n_gpu = torch.cuda.device_count()
+ logger.info("device: {}, n_gpu {}".format(device, n_gpu))
+
+ if not args.do_train and not args.do_eval:
+ raise ValueError("At least one of `do_train` or `do_eval` must be True.")
+
+ if not os.path.exists(args.output_dir):
+ os.makedirs(args.output_dir)
+
+ # Load tokenizer and model
+ # This loading functions also add new tokens and embeddings called `special tokens`
+ # These new embeddings will be fine-tuned on the RocStories dataset
+ special_tokens = ["_start_", "_delimiter_", "_classify_"]
+ tokenizer = OpenAIGPTTokenizer.from_pretrained(args.model_name)
+ tokenizer.add_tokens(special_tokens)
+ special_tokens_ids = tokenizer.convert_tokens_to_ids(special_tokens)
+ model = OpenAIGPTDoubleHeadsModel.from_pretrained(args.model_name)
+ model.resize_token_embeddings(len(tokenizer))
+ model.to(device)
+
+ # Load and encode the datasets
+ def tokenize_and_encode(obj):
+ """Tokenize and encode a nested object"""
+ if isinstance(obj, str):
+ return tokenizer.convert_tokens_to_ids(tokenizer.tokenize(obj))
+ elif isinstance(obj, int):
+ return obj
+ return [tokenize_and_encode(o) for o in obj]
+
+ logger.info("Encoding dataset...")
+ train_dataset = load_rocstories_dataset(args.train_dataset)
+ eval_dataset = load_rocstories_dataset(args.eval_dataset)
+ datasets = (train_dataset, eval_dataset)
+ encoded_datasets = tokenize_and_encode(datasets)
+
+ # Compute the max input length for the Transformer
+ max_length = model.config.n_positions // 2 - 2
+ input_length = max(
+ len(story[:max_length]) + max(len(cont1[:max_length]), len(cont2[:max_length])) + 3
+ for dataset in encoded_datasets
+ for story, cont1, cont2, _ in dataset
+ )
+ input_length = min(input_length, model.config.n_positions) # Max size of input for the pre-trained model
+
+ # Prepare inputs tensors and dataloaders
+ tensor_datasets = pre_process_datasets(encoded_datasets, input_length, max_length, *special_tokens_ids)
+ train_tensor_dataset, eval_tensor_dataset = tensor_datasets[0], tensor_datasets[1]
+
+ train_data = TensorDataset(*train_tensor_dataset)
+ train_sampler = RandomSampler(train_data)
+ train_dataloader = DataLoader(train_data, sampler=train_sampler, batch_size=args.train_batch_size)
+
+ eval_data = TensorDataset(*eval_tensor_dataset)
+ eval_sampler = SequentialSampler(eval_data)
+ eval_dataloader = DataLoader(eval_data, sampler=eval_sampler, batch_size=args.eval_batch_size)
+
+ # Prepare optimizer
+ if args.do_train:
+ if args.max_steps > 0:
+ t_total = args.max_steps
+ args.num_train_epochs = args.max_steps // (len(train_dataloader) // args.gradient_accumulation_steps) + 1
+ else:
+ t_total = len(train_dataloader) // args.gradient_accumulation_steps * args.num_train_epochs
+
+ param_optimizer = list(model.named_parameters())
+ no_decay = ["bias", "LayerNorm.bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in param_optimizer if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {"params": [p for n, p in param_optimizer if any(nd in n for nd in no_decay)], "weight_decay": 0.0},
+ ]
+ optimizer = AdamW(optimizer_grouped_parameters, lr=args.learning_rate, eps=args.adam_epsilon)
+ scheduler = get_linear_schedule_with_warmup(
+ optimizer, num_warmup_steps=args.warmup_steps, num_training_steps=t_total
+ )
+
+ if args.do_train:
+ nb_tr_steps, tr_loss, exp_average_loss = 0, 0, None
+ model.train()
+ for _ in trange(int(args.num_train_epochs), desc="Epoch"):
+ tr_loss = 0
+ nb_tr_steps = 0
+ tqdm_bar = tqdm(train_dataloader, desc="Training")
+ for step, batch in enumerate(tqdm_bar):
+ batch = tuple(t.to(device) for t in batch)
+ input_ids, mc_token_ids, lm_labels, mc_labels = batch
+ losses = model(input_ids, mc_token_ids=mc_token_ids, lm_labels=lm_labels, mc_labels=mc_labels)
+ loss = args.lm_coef * losses[0] + losses[1]
+ loss.backward()
+ optimizer.step()
+ scheduler.step()
+ optimizer.zero_grad()
+ tr_loss += loss.item()
+ exp_average_loss = (
+ loss.item() if exp_average_loss is None else 0.7 * exp_average_loss + 0.3 * loss.item()
+ )
+ nb_tr_steps += 1
+ tqdm_bar.desc = "Training loss: {:.2e} lr: {:.2e}".format(exp_average_loss, scheduler.get_lr()[0])
+
+ # Save a trained model
+ if args.do_train:
+ # Save a trained model, configuration and tokenizer
+ model_to_save = model.module if hasattr(model, "module") else model # Only save the model itself
+
+ # If we save using the predefined names, we can load using `from_pretrained`
+ output_model_file = os.path.join(args.output_dir, WEIGHTS_NAME)
+ output_config_file = os.path.join(args.output_dir, CONFIG_NAME)
+
+ torch.save(model_to_save.state_dict(), output_model_file)
+ model_to_save.config.to_json_file(output_config_file)
+ tokenizer.save_vocabulary(args.output_dir)
+
+ # Load a trained model and vocabulary that you have fine-tuned
+ model = OpenAIGPTDoubleHeadsModel.from_pretrained(args.output_dir)
+ tokenizer = OpenAIGPTTokenizer.from_pretrained(args.output_dir)
+ model.to(device)
+
+ if args.do_eval:
+ model.eval()
+ eval_loss, eval_accuracy = 0, 0
+ nb_eval_steps, nb_eval_examples = 0, 0
+ for batch in tqdm(eval_dataloader, desc="Evaluating"):
+ batch = tuple(t.to(device) for t in batch)
+ input_ids, mc_token_ids, lm_labels, mc_labels = batch
+ with torch.no_grad():
+ _, mc_loss, _, mc_logits = model(
+ input_ids, mc_token_ids=mc_token_ids, lm_labels=lm_labels, mc_labels=mc_labels
+ )
+
+ mc_logits = mc_logits.detach().cpu().numpy()
+ mc_labels = mc_labels.to("cpu").numpy()
+ tmp_eval_accuracy = accuracy(mc_logits, mc_labels)
+
+ eval_loss += mc_loss.mean().item()
+ eval_accuracy += tmp_eval_accuracy
+
+ nb_eval_examples += input_ids.size(0)
+ nb_eval_steps += 1
+
+ eval_loss = eval_loss / nb_eval_steps
+ eval_accuracy = eval_accuracy / nb_eval_examples
+ train_loss = tr_loss / nb_tr_steps if args.do_train else None
+ result = {"eval_loss": eval_loss, "eval_accuracy": eval_accuracy, "train_loss": train_loss}
+
+ output_eval_file = os.path.join(args.output_dir, "eval_results.txt")
+ with open(output_eval_file, "w") as writer:
+ logger.info("***** Eval results *****")
+ for key in sorted(result.keys()):
+ logger.info(" %s = %s", key, str(result[key]))
+ writer.write("%s = %s\n" % (key, str(result[key])))
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_swag.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_swag.py
new file mode 100644
index 0000000000000000000000000000000000000000..dbf712a71ff200bc9d8ca0ee2c1ea4f83af533fa
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_swag.py
@@ -0,0 +1,723 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""BERT finetuning runner.
+Finetuning the library models for multiple choice on SWAG (Bert).
+"""
+
+import argparse
+import csv
+import glob
+import logging
+import os
+import random
+
+import numpy as np
+import torch
+from torch.utils.data import DataLoader, RandomSampler, SequentialSampler, TensorDataset
+from torch.utils.data.distributed import DistributedSampler
+from tqdm import tqdm, trange
+
+import transformers
+from transformers import (
+ WEIGHTS_NAME,
+ AdamW,
+ AutoConfig,
+ AutoModelForMultipleChoice,
+ AutoTokenizer,
+ get_linear_schedule_with_warmup,
+)
+from transformers.trainer_utils import is_main_process
+
+
+try:
+ from torch.utils.tensorboard import SummaryWriter
+except ImportError:
+ from tensorboardX import SummaryWriter
+
+
+logger = logging.getLogger(__name__)
+
+
+class SwagExample(object):
+ """A single training/test example for the SWAG dataset."""
+
+ def __init__(self, swag_id, context_sentence, start_ending, ending_0, ending_1, ending_2, ending_3, label=None):
+ self.swag_id = swag_id
+ self.context_sentence = context_sentence
+ self.start_ending = start_ending
+ self.endings = [
+ ending_0,
+ ending_1,
+ ending_2,
+ ending_3,
+ ]
+ self.label = label
+
+ def __str__(self):
+ return self.__repr__()
+
+ def __repr__(self):
+ attributes = [
+ "swag_id: {}".format(self.swag_id),
+ "context_sentence: {}".format(self.context_sentence),
+ "start_ending: {}".format(self.start_ending),
+ "ending_0: {}".format(self.endings[0]),
+ "ending_1: {}".format(self.endings[1]),
+ "ending_2: {}".format(self.endings[2]),
+ "ending_3: {}".format(self.endings[3]),
+ ]
+
+ if self.label is not None:
+ attributes.append("label: {}".format(self.label))
+
+ return ", ".join(attributes)
+
+
+class InputFeatures(object):
+ def __init__(self, example_id, choices_features, label):
+ self.example_id = example_id
+ self.choices_features = [
+ {"input_ids": input_ids, "input_mask": input_mask, "segment_ids": segment_ids}
+ for _, input_ids, input_mask, segment_ids in choices_features
+ ]
+ self.label = label
+
+
+def read_swag_examples(input_file, is_training=True):
+ with open(input_file, "r", encoding="utf-8") as f:
+ lines = list(csv.reader(f))
+
+ if is_training and lines[0][-1] != "label":
+ raise ValueError("For training, the input file must contain a label column.")
+
+ examples = [
+ SwagExample(
+ swag_id=line[2],
+ context_sentence=line[4],
+ start_ending=line[5], # in the swag dataset, the
+ # common beginning of each
+ # choice is stored in "sent2".
+ ending_0=line[7],
+ ending_1=line[8],
+ ending_2=line[9],
+ ending_3=line[10],
+ label=int(line[11]) if is_training else None,
+ )
+ for line in lines[1:] # we skip the line with the column names
+ ]
+
+ return examples
+
+
+def convert_examples_to_features(examples, tokenizer, max_seq_length, is_training):
+ """Loads a data file into a list of `InputBatch`s."""
+
+ # Swag is a multiple choice task. To perform this task using Bert,
+ # we will use the formatting proposed in "Improving Language
+ # Understanding by Generative Pre-Training" and suggested by
+ # @jacobdevlin-google in this issue
+ # https://github.com/google-research/bert/issues/38.
+ #
+ # Each choice will correspond to a sample on which we run the
+ # inference. For a given Swag example, we will create the 4
+ # following inputs:
+ # - [CLS] context [SEP] choice_1 [SEP]
+ # - [CLS] context [SEP] choice_2 [SEP]
+ # - [CLS] context [SEP] choice_3 [SEP]
+ # - [CLS] context [SEP] choice_4 [SEP]
+ # The model will output a single value for each input. To get the
+ # final decision of the model, we will run a softmax over these 4
+ # outputs.
+ features = []
+ for example_index, example in tqdm(enumerate(examples)):
+ context_tokens = tokenizer.tokenize(example.context_sentence)
+ start_ending_tokens = tokenizer.tokenize(example.start_ending)
+
+ choices_features = []
+ for ending_index, ending in enumerate(example.endings):
+ # We create a copy of the context tokens in order to be
+ # able to shrink it according to ending_tokens
+ context_tokens_choice = context_tokens[:]
+ ending_tokens = start_ending_tokens + tokenizer.tokenize(ending)
+ # Modifies `context_tokens_choice` and `ending_tokens` in
+ # place so that the total length is less than the
+ # specified length. Account for [CLS], [SEP], [SEP] with
+ # "- 3"
+ _truncate_seq_pair(context_tokens_choice, ending_tokens, max_seq_length - 3)
+
+ tokens = ["[CLS]"] + context_tokens_choice + ["[SEP]"] + ending_tokens + ["[SEP]"]
+ segment_ids = [0] * (len(context_tokens_choice) + 2) + [1] * (len(ending_tokens) + 1)
+
+ input_ids = tokenizer.convert_tokens_to_ids(tokens)
+ input_mask = [1] * len(input_ids)
+
+ # Zero-pad up to the sequence length.
+ padding = [0] * (max_seq_length - len(input_ids))
+ input_ids += padding
+ input_mask += padding
+ segment_ids += padding
+
+ assert len(input_ids) == max_seq_length
+ assert len(input_mask) == max_seq_length
+ assert len(segment_ids) == max_seq_length
+
+ choices_features.append((tokens, input_ids, input_mask, segment_ids))
+
+ label = example.label
+ if example_index < 5:
+ logger.info("*** Example ***")
+ logger.info("swag_id: {}".format(example.swag_id))
+ for choice_idx, (tokens, input_ids, input_mask, segment_ids) in enumerate(choices_features):
+ logger.info("choice: {}".format(choice_idx))
+ logger.info("tokens: {}".format(" ".join(tokens)))
+ logger.info("input_ids: {}".format(" ".join(map(str, input_ids))))
+ logger.info("input_mask: {}".format(" ".join(map(str, input_mask))))
+ logger.info("segment_ids: {}".format(" ".join(map(str, segment_ids))))
+ if is_training:
+ logger.info("label: {}".format(label))
+
+ features.append(InputFeatures(example_id=example.swag_id, choices_features=choices_features, label=label))
+
+ return features
+
+
+def _truncate_seq_pair(tokens_a, tokens_b, max_length):
+ """Truncates a sequence pair in place to the maximum length."""
+
+ # This is a simple heuristic which will always truncate the longer sequence
+ # one token at a time. This makes more sense than truncating an equal percent
+ # of tokens from each, since if one sequence is very short then each token
+ # that's truncated likely contains more information than a longer sequence.
+ while True:
+ total_length = len(tokens_a) + len(tokens_b)
+ if total_length <= max_length:
+ break
+ if len(tokens_a) > len(tokens_b):
+ tokens_a.pop()
+ else:
+ tokens_b.pop()
+
+
+def accuracy(out, labels):
+ outputs = np.argmax(out, axis=1)
+ return np.sum(outputs == labels)
+
+
+def select_field(features, field):
+ return [[choice[field] for choice in feature.choices_features] for feature in features]
+
+
+def set_seed(args):
+ random.seed(args.seed)
+ np.random.seed(args.seed)
+ torch.manual_seed(args.seed)
+ if args.n_gpu > 0:
+ torch.cuda.manual_seed_all(args.seed)
+
+
+def load_and_cache_examples(args, tokenizer, evaluate=False, output_examples=False):
+ if args.local_rank not in [-1, 0]:
+ torch.distributed.barrier() # Make sure only the first process in distributed training process the dataset, and the others will use the cache
+
+ # Load data features from cache or dataset file
+ input_file = args.predict_file if evaluate else args.train_file
+ cached_features_file = os.path.join(
+ os.path.dirname(input_file),
+ "cached_{}_{}_{}".format(
+ "dev" if evaluate else "train",
+ list(filter(None, args.model_name_or_path.split("/"))).pop(),
+ str(args.max_seq_length),
+ ),
+ )
+ if os.path.exists(cached_features_file) and not args.overwrite_cache and not output_examples:
+ logger.info("Loading features from cached file %s", cached_features_file)
+ features = torch.load(cached_features_file)
+ else:
+ logger.info("Creating features from dataset file at %s", input_file)
+ examples = read_swag_examples(input_file)
+ features = convert_examples_to_features(examples, tokenizer, args.max_seq_length, not evaluate)
+
+ if args.local_rank in [-1, 0]:
+ logger.info("Saving features into cached file %s", cached_features_file)
+ torch.save(features, cached_features_file)
+
+ if args.local_rank == 0:
+ torch.distributed.barrier() # Make sure only the first process in distributed training process the dataset, and the others will use the cache
+
+ # Convert to Tensors and build dataset
+ all_input_ids = torch.tensor(select_field(features, "input_ids"), dtype=torch.long)
+ all_input_mask = torch.tensor(select_field(features, "input_mask"), dtype=torch.long)
+ all_segment_ids = torch.tensor(select_field(features, "segment_ids"), dtype=torch.long)
+ all_label = torch.tensor([f.label for f in features], dtype=torch.long)
+
+ if evaluate:
+ dataset = TensorDataset(all_input_ids, all_input_mask, all_segment_ids, all_label)
+ else:
+ dataset = TensorDataset(all_input_ids, all_input_mask, all_segment_ids, all_label)
+
+ if output_examples:
+ return dataset, examples, features
+ return dataset
+
+
+def train(args, train_dataset, model, tokenizer):
+ """Train the model"""
+ if args.local_rank in [-1, 0]:
+ tb_writer = SummaryWriter()
+
+ args.train_batch_size = args.per_gpu_train_batch_size * max(1, args.n_gpu)
+ train_sampler = RandomSampler(train_dataset) if args.local_rank == -1 else DistributedSampler(train_dataset)
+ train_dataloader = DataLoader(train_dataset, sampler=train_sampler, batch_size=args.train_batch_size)
+
+ if args.max_steps > 0:
+ t_total = args.max_steps
+ args.num_train_epochs = args.max_steps // (len(train_dataloader) // args.gradient_accumulation_steps) + 1
+ else:
+ t_total = len(train_dataloader) // args.gradient_accumulation_steps * args.num_train_epochs
+
+ # Prepare optimizer and schedule (linear warmup and decay)
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {"params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)], "weight_decay": 0.0},
+ ]
+ optimizer = AdamW(optimizer_grouped_parameters, lr=args.learning_rate, eps=args.adam_epsilon)
+ scheduler = get_linear_schedule_with_warmup(
+ optimizer, num_warmup_steps=args.warmup_steps, num_training_steps=t_total
+ )
+ if args.fp16:
+ try:
+ from apex import amp
+ except ImportError:
+ raise ImportError("Please install apex from https://www.github.com/nvidia/apex to use fp16 training.")
+ model, optimizer = amp.initialize(model, optimizer, opt_level=args.fp16_opt_level)
+
+ # multi-gpu training (should be after apex fp16 initialization)
+ if args.n_gpu > 1:
+ model = torch.nn.DataParallel(model)
+
+ # Distributed training (should be after apex fp16 initialization)
+ if args.local_rank != -1:
+ model = torch.nn.parallel.DistributedDataParallel(
+ model, device_ids=[args.local_rank], output_device=args.local_rank, find_unused_parameters=True
+ )
+
+ # Train!
+ logger.info("***** Running training *****")
+ logger.info(" Num examples = %d", len(train_dataset))
+ logger.info(" Num Epochs = %d", args.num_train_epochs)
+ logger.info(" Instantaneous batch size per GPU = %d", args.per_gpu_train_batch_size)
+ logger.info(
+ " Total train batch size (w. parallel, distributed & accumulation) = %d",
+ args.train_batch_size
+ * args.gradient_accumulation_steps
+ * (torch.distributed.get_world_size() if args.local_rank != -1 else 1),
+ )
+ logger.info(" Gradient Accumulation steps = %d", args.gradient_accumulation_steps)
+ logger.info(" Total optimization steps = %d", t_total)
+
+ global_step = 0
+ tr_loss, logging_loss = 0.0, 0.0
+ model.zero_grad()
+ train_iterator = trange(int(args.num_train_epochs), desc="Epoch", disable=args.local_rank not in [-1, 0])
+ set_seed(args) # Added here for reproducibility
+ for _ in train_iterator:
+ epoch_iterator = tqdm(train_dataloader, desc="Iteration", disable=args.local_rank not in [-1, 0])
+ for step, batch in enumerate(epoch_iterator):
+ model.train()
+ batch = tuple(t.to(args.device) for t in batch)
+ inputs = {
+ "input_ids": batch[0],
+ "attention_mask": batch[1],
+ # 'token_type_ids': None if args.model_type == 'xlm' else batch[2],
+ "token_type_ids": batch[2],
+ "labels": batch[3],
+ }
+ # if args.model_type in ['xlnet', 'xlm']:
+ # inputs.update({'cls_index': batch[5],
+ # 'p_mask': batch[6]})
+ outputs = model(**inputs)
+ loss = outputs[0] # model outputs are always tuple in transformers (see doc)
+
+ if args.n_gpu > 1:
+ loss = loss.mean() # mean() to average on multi-gpu parallel (not distributed) training
+ if args.gradient_accumulation_steps > 1:
+ loss = loss / args.gradient_accumulation_steps
+
+ if args.fp16:
+ with amp.scale_loss(loss, optimizer) as scaled_loss:
+ scaled_loss.backward()
+ torch.nn.utils.clip_grad_norm_(amp.master_params(optimizer), args.max_grad_norm)
+ else:
+ loss.backward()
+ torch.nn.utils.clip_grad_norm_(model.parameters(), args.max_grad_norm)
+
+ tr_loss += loss.item()
+ if (step + 1) % args.gradient_accumulation_steps == 0:
+ optimizer.step()
+ scheduler.step() # Update learning rate schedule
+ model.zero_grad()
+ global_step += 1
+
+ if args.local_rank in [-1, 0] and args.logging_steps > 0 and global_step % args.logging_steps == 0:
+ # Log metrics
+ if (
+ args.local_rank == -1 and args.evaluate_during_training
+ ): # Only evaluate when single GPU otherwise metrics may not average well
+ results = evaluate(args, model, tokenizer)
+ for key, value in results.items():
+ tb_writer.add_scalar("eval_{}".format(key), value, global_step)
+ tb_writer.add_scalar("lr", scheduler.get_lr()[0], global_step)
+ tb_writer.add_scalar("loss", (tr_loss - logging_loss) / args.logging_steps, global_step)
+ logging_loss = tr_loss
+
+ if args.local_rank in [-1, 0] and args.save_steps > 0 and global_step % args.save_steps == 0:
+ # Save model checkpoint
+ output_dir = os.path.join(args.output_dir, "checkpoint-{}".format(global_step))
+ model_to_save = (
+ model.module if hasattr(model, "module") else model
+ ) # Take care of distributed/parallel training
+ model_to_save.save_pretrained(output_dir)
+ tokenizer.save_vocabulary(output_dir)
+ torch.save(args, os.path.join(output_dir, "training_args.bin"))
+ logger.info("Saving model checkpoint to %s", output_dir)
+
+ if args.max_steps > 0 and global_step > args.max_steps:
+ epoch_iterator.close()
+ break
+ if args.max_steps > 0 and global_step > args.max_steps:
+ train_iterator.close()
+ break
+
+ if args.local_rank in [-1, 0]:
+ tb_writer.close()
+
+ return global_step, tr_loss / global_step
+
+
+def evaluate(args, model, tokenizer, prefix=""):
+ dataset, examples, features = load_and_cache_examples(args, tokenizer, evaluate=True, output_examples=True)
+
+ if not os.path.exists(args.output_dir) and args.local_rank in [-1, 0]:
+ os.makedirs(args.output_dir)
+
+ args.eval_batch_size = args.per_gpu_eval_batch_size * max(1, args.n_gpu)
+ # Note that DistributedSampler samples randomly
+ eval_sampler = SequentialSampler(dataset) if args.local_rank == -1 else DistributedSampler(dataset)
+ eval_dataloader = DataLoader(dataset, sampler=eval_sampler, batch_size=args.eval_batch_size)
+
+ # Eval!
+ logger.info("***** Running evaluation {} *****".format(prefix))
+ logger.info(" Num examples = %d", len(dataset))
+ logger.info(" Batch size = %d", args.eval_batch_size)
+
+ eval_loss, eval_accuracy = 0, 0
+ nb_eval_steps, nb_eval_examples = 0, 0
+
+ for batch in tqdm(eval_dataloader, desc="Evaluating"):
+ model.eval()
+ batch = tuple(t.to(args.device) for t in batch)
+ with torch.no_grad():
+ inputs = {
+ "input_ids": batch[0],
+ "attention_mask": batch[1],
+ # 'token_type_ids': None if args.model_type == 'xlm' else batch[2] # XLM don't use segment_ids
+ "token_type_ids": batch[2],
+ "labels": batch[3],
+ }
+
+ # if args.model_type in ['xlnet', 'xlm']:
+ # inputs.update({'cls_index': batch[4],
+ # 'p_mask': batch[5]})
+ outputs = model(**inputs)
+ tmp_eval_loss, logits = outputs[:2]
+ eval_loss += tmp_eval_loss.mean().item()
+
+ logits = logits.detach().cpu().numpy()
+ label_ids = inputs["labels"].to("cpu").numpy()
+ tmp_eval_accuracy = accuracy(logits, label_ids)
+ eval_accuracy += tmp_eval_accuracy
+
+ nb_eval_steps += 1
+ nb_eval_examples += inputs["input_ids"].size(0)
+
+ eval_loss = eval_loss / nb_eval_steps
+ eval_accuracy = eval_accuracy / nb_eval_examples
+ result = {"eval_loss": eval_loss, "eval_accuracy": eval_accuracy}
+
+ output_eval_file = os.path.join(args.output_dir, "eval_results.txt")
+ with open(output_eval_file, "w") as writer:
+ logger.info("***** Eval results *****")
+ for key in sorted(result.keys()):
+ logger.info("%s = %s", key, str(result[key]))
+ writer.write("%s = %s\n" % (key, str(result[key])))
+
+ return result
+
+
+def main():
+ parser = argparse.ArgumentParser()
+
+ # Required parameters
+ parser.add_argument(
+ "--train_file", default=None, type=str, required=True, help="SWAG csv for training. E.g., train.csv"
+ )
+ parser.add_argument(
+ "--predict_file",
+ default=None,
+ type=str,
+ required=True,
+ help="SWAG csv for predictions. E.g., val.csv or test.csv",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ default=None,
+ type=str,
+ required=True,
+ help="Path to pretrained model or model identifier from huggingface.co/models",
+ )
+ parser.add_argument(
+ "--output_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The output directory where the model checkpoints and predictions will be written.",
+ )
+
+ # Other parameters
+ parser.add_argument(
+ "--config_name", default="", type=str, help="Pretrained config name or path if not the same as model_name"
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ default="",
+ type=str,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--max_seq_length",
+ default=384,
+ type=int,
+ help=(
+ "The maximum total input sequence length after tokenization. Sequences "
+ "longer than this will be truncated, and sequences shorter than this will be padded."
+ ),
+ )
+ parser.add_argument("--do_train", action="store_true", help="Whether to run training.")
+ parser.add_argument("--do_eval", action="store_true", help="Whether to run eval on the dev set.")
+ parser.add_argument(
+ "--evaluate_during_training", action="store_true", help="Rul evaluation during training at each logging step."
+ )
+
+ parser.add_argument("--per_gpu_train_batch_size", default=8, type=int, help="Batch size per GPU/CPU for training.")
+ parser.add_argument(
+ "--per_gpu_eval_batch_size", default=8, type=int, help="Batch size per GPU/CPU for evaluation."
+ )
+ parser.add_argument("--learning_rate", default=5e-5, type=float, help="The initial learning rate for Adam.")
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument("--weight_decay", default=0.0, type=float, help="Weight decay if we apply some.")
+ parser.add_argument("--adam_epsilon", default=1e-8, type=float, help="Epsilon for Adam optimizer.")
+ parser.add_argument("--max_grad_norm", default=1.0, type=float, help="Max gradient norm.")
+ parser.add_argument(
+ "--num_train_epochs", default=3.0, type=float, help="Total number of training epochs to perform."
+ )
+ parser.add_argument(
+ "--max_steps",
+ default=-1,
+ type=int,
+ help="If > 0: set total number of training steps to perform. Override num_train_epochs.",
+ )
+ parser.add_argument("--warmup_steps", default=0, type=int, help="Linear warmup over warmup_steps.")
+
+ parser.add_argument("--logging_steps", type=int, default=50, help="Log every X updates steps.")
+ parser.add_argument("--save_steps", type=int, default=50, help="Save checkpoint every X updates steps.")
+ parser.add_argument(
+ "--eval_all_checkpoints",
+ action="store_true",
+ help="Evaluate all checkpoints starting with the same prefix as model_name ending and ending with step number",
+ )
+ parser.add_argument("--no_cuda", action="store_true", help="Whether not to use CUDA when available")
+ parser.add_argument(
+ "--overwrite_output_dir", action="store_true", help="Overwrite the content of the output directory"
+ )
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+ parser.add_argument("--seed", type=int, default=42, help="random seed for initialization")
+
+ parser.add_argument("--local_rank", type=int, default=-1, help="local_rank for distributed training on gpus")
+ parser.add_argument(
+ "--fp16",
+ action="store_true",
+ help="Whether to use 16-bit (mixed) precision (through NVIDIA apex) instead of 32-bit",
+ )
+ parser.add_argument(
+ "--fp16_opt_level",
+ type=str,
+ default="O1",
+ help=(
+ "For fp16: Apex AMP optimization level selected in ['O0', 'O1', 'O2', and 'O3']. "
+ "See details at https://nvidia.github.io/apex/amp.html"
+ ),
+ )
+ parser.add_argument("--server_ip", type=str, default="", help="Can be used for distant debugging.")
+ parser.add_argument("--server_port", type=str, default="", help="Can be used for distant debugging.")
+ args = parser.parse_args()
+
+ if (
+ os.path.exists(args.output_dir)
+ and os.listdir(args.output_dir)
+ and args.do_train
+ and not args.overwrite_output_dir
+ ):
+ raise ValueError(
+ "Output directory ({}) already exists and is not empty. Use --overwrite_output_dir to overcome.".format(
+ args.output_dir
+ )
+ )
+
+ # Setup distant debugging if needed
+ if args.server_ip and args.server_port:
+ # Distant debugging - see https://code.visualstudio.com/docs/python/debugging#_attach-to-a-local-script
+ import ptvsd
+
+ print("Waiting for debugger attach")
+ ptvsd.enable_attach(address=(args.server_ip, args.server_port), redirect_output=True)
+ ptvsd.wait_for_attach()
+
+ # Setup CUDA, GPU & distributed training
+ if args.local_rank == -1 or args.no_cuda:
+ device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
+ args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
+ else: # Initializes the distributed backend which will take care of synchronizing nodes/GPUs
+ torch.cuda.set_device(args.local_rank)
+ device = torch.device("cuda", args.local_rank)
+ torch.distributed.init_process_group(backend="nccl")
+ args.n_gpu = 1
+ args.device = device
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO if args.local_rank in [-1, 0] else logging.WARN,
+ )
+ logger.warning(
+ "Process rank: %s, device: %s, n_gpu: %s, distributed training: %s, 16-bits training: %s",
+ args.local_rank,
+ device,
+ args.n_gpu,
+ bool(args.local_rank != -1),
+ args.fp16,
+ )
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ if is_main_process(args.local_rank):
+ transformers.utils.logging.set_verbosity_info()
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Set seed
+ set_seed(args)
+
+ # Load pretrained model and tokenizer
+ if args.local_rank not in [-1, 0]:
+ torch.distributed.barrier() # Make sure only the first process in distributed training will download model & vocab
+
+ config = AutoConfig.from_pretrained(args.config_name if args.config_name else args.model_name_or_path)
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.tokenizer_name if args.tokenizer_name else args.model_name_or_path,
+ )
+ model = AutoModelForMultipleChoice.from_pretrained(
+ args.model_name_or_path, from_tf=bool(".ckpt" in args.model_name_or_path), config=config
+ )
+
+ if args.local_rank == 0:
+ torch.distributed.barrier() # Make sure only the first process in distributed training will download model & vocab
+
+ model.to(args.device)
+
+ logger.info("Training/evaluation parameters %s", args)
+
+ # Training
+ if args.do_train:
+ train_dataset = load_and_cache_examples(args, tokenizer, evaluate=False, output_examples=False)
+ global_step, tr_loss = train(args, train_dataset, model, tokenizer)
+ logger.info(" global_step = %s, average loss = %s", global_step, tr_loss)
+
+ # Save the trained model and the tokenizer
+ if args.local_rank == -1 or torch.distributed.get_rank() == 0:
+ logger.info("Saving model checkpoint to %s", args.output_dir)
+ # Save a trained model, configuration and tokenizer using `save_pretrained()`.
+ # They can then be reloaded using `from_pretrained()`
+ model_to_save = (
+ model.module if hasattr(model, "module") else model
+ ) # Take care of distributed/parallel training
+ model_to_save.save_pretrained(args.output_dir)
+ tokenizer.save_pretrained(args.output_dir)
+
+ # Good practice: save your training arguments together with the trained model
+ torch.save(args, os.path.join(args.output_dir, "training_args.bin"))
+
+ # Load a trained model and vocabulary that you have fine-tuned
+ model = AutoModelForMultipleChoice.from_pretrained(args.output_dir)
+ tokenizer = AutoTokenizer.from_pretrained(args.output_dir)
+ model.to(args.device)
+
+ # Evaluation - we can ask to evaluate all the checkpoints (sub-directories) in a directory
+ results = {}
+ if args.do_eval and args.local_rank in [-1, 0]:
+ if args.do_train:
+ checkpoints = [args.output_dir]
+ else:
+ # if do_train is False and do_eval is true, load model directly from pretrained.
+ checkpoints = [args.model_name_or_path]
+
+ if args.eval_all_checkpoints:
+ checkpoints = [
+ os.path.dirname(c) for c in sorted(glob.glob(args.output_dir + "/**/" + WEIGHTS_NAME, recursive=True))
+ ]
+
+ logger.info("Evaluate the following checkpoints: %s", checkpoints)
+
+ for checkpoint in checkpoints:
+ # Reload the model
+ global_step = checkpoint.split("-")[-1] if len(checkpoints) > 1 else ""
+ model = AutoModelForMultipleChoice.from_pretrained(checkpoint)
+ tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+ model.to(args.device)
+
+ # Evaluate
+ result = evaluate(args, model, tokenizer, prefix=global_step)
+
+ result = {k + ("_{}".format(global_step) if global_step else ""): v for k, v in result.items()}
+ results.update(result)
+
+ logger.info("Results: {}".format(results))
+
+ return results
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_transfo_xl.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_transfo_xl.py
new file mode 100644
index 0000000000000000000000000000000000000000..ce24fe13d792315c2a042497b3181d200fe084a7
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/run_transfo_xl.py
@@ -0,0 +1,144 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2018 Google AI, Google Brain and Carnegie Mellon University Authors and the HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch Transformer XL model evaluation script.
+Adapted from https://github.com/kimiyoung/transformer-xl.
+In particular https://github.com/kimiyoung/transformer-xl/blob/master/pytorch/eval.py
+
+This script with default values evaluates a pretrained Transformer-XL on WikiText 103
+"""
+
+import argparse
+import logging
+import math
+import time
+
+import torch
+
+from transformers import TransfoXLCorpus, TransfoXLLMHeadModel
+
+
+logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s", datefmt="%m/%d/%Y %H:%M:%S", level=logging.INFO
+)
+logger = logging.getLogger(__name__)
+
+
+def main():
+ parser = argparse.ArgumentParser(description="PyTorch Transformer Language Model")
+ parser.add_argument("--model_name", type=str, default="transfo-xl/transfo-xl-wt103", help="pretrained model name")
+ parser.add_argument(
+ "--split", type=str, default="test", choices=["all", "valid", "test"], help="which split to evaluate"
+ )
+ parser.add_argument("--batch_size", type=int, default=10, help="batch size")
+ parser.add_argument("--tgt_len", type=int, default=128, help="number of tokens to predict")
+ parser.add_argument("--ext_len", type=int, default=0, help="length of the extended context")
+ parser.add_argument("--mem_len", type=int, default=1600, help="length of the retained previous heads")
+ parser.add_argument("--clamp_len", type=int, default=1000, help="max positional embedding index")
+ parser.add_argument("--no_cuda", action="store_true", help="Do not use CUDA even though CUA is available")
+ parser.add_argument("--work_dir", type=str, required=True, help="path to the work_dir")
+ parser.add_argument("--no_log", action="store_true", help="do not log the eval result")
+ parser.add_argument("--same_length", action="store_true", help="set same length attention with masking")
+ parser.add_argument("--server_ip", type=str, default="", help="Can be used for distant debugging.")
+ parser.add_argument("--server_port", type=str, default="", help="Can be used for distant debugging.")
+ args = parser.parse_args()
+ assert args.ext_len >= 0, "extended context length must be non-negative"
+
+ if args.server_ip and args.server_port:
+ # Distant debugging - see https://code.visualstudio.com/docs/python/debugging#_attach-to-a-local-script
+ import ptvsd
+
+ print("Waiting for debugger attach")
+ ptvsd.enable_attach(address=(args.server_ip, args.server_port), redirect_output=True)
+ ptvsd.wait_for_attach()
+
+ device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
+ logger.info("device: {}".format(device))
+
+ # Load a pre-processed dataset
+ # You can also build the corpus yourself using TransfoXLCorpus methods
+ # The pre-processing involve computing word frequencies to prepare the Adaptive input and SoftMax
+ # and tokenizing the dataset
+ # The pre-processed corpus is a convertion (using the conversion script )
+ corpus = TransfoXLCorpus.from_pretrained(args.model_name)
+
+ va_iter = corpus.get_iterator("valid", args.batch_size, args.tgt_len, device=device, ext_len=args.ext_len)
+ te_iter = corpus.get_iterator("test", args.batch_size, args.tgt_len, device=device, ext_len=args.ext_len)
+
+ # Load a pre-trained model
+ model = TransfoXLLMHeadModel.from_pretrained(args.model_name)
+ model.to(device)
+
+ logger.info(
+ "Evaluating with bsz {} tgt_len {} ext_len {} mem_len {} clamp_len {}".format(
+ args.batch_size, args.tgt_len, args.ext_len, args.mem_len, args.clamp_len
+ )
+ )
+
+ model.reset_memory_length(args.mem_len)
+ if args.clamp_len > 0:
+ model.clamp_len = args.clamp_len
+ if args.same_length:
+ model.same_length = True
+
+ ###############################################################################
+ # Evaluation code
+ ###############################################################################
+ def evaluate(eval_iter):
+ # Turn on evaluation mode which disables dropout.
+ model.eval()
+ total_len, total_loss = 0, 0.0
+ start_time = time.time()
+ with torch.no_grad():
+ mems = None
+ for idx, (data, target, seq_len) in enumerate(eval_iter):
+ ret = model(data, lm_labels=target, mems=mems)
+ loss, _, mems = ret
+ loss = loss.mean()
+ total_loss += seq_len * loss.item()
+ total_len += seq_len
+ total_time = time.time() - start_time
+ logger.info("Time : {:.2f}s, {:.2f}ms/segment".format(total_time, 1000 * total_time / (idx + 1)))
+ return total_loss / total_len
+
+ # Run on test data.
+ if args.split == "all":
+ test_loss = evaluate(te_iter)
+ valid_loss = evaluate(va_iter)
+ elif args.split == "valid":
+ valid_loss = evaluate(va_iter)
+ test_loss = None
+ elif args.split == "test":
+ test_loss = evaluate(te_iter)
+ valid_loss = None
+
+ def format_log(loss, split):
+ log_str = "| {0} loss {1:5.2f} | {0} ppl {2:9.3f} ".format(split, loss, math.exp(loss))
+ return log_str
+
+ log_str = ""
+ if valid_loss is not None:
+ log_str += format_log(valid_loss, "valid")
+ if test_loss is not None:
+ log_str += format_log(test_loss, "test")
+
+ logger.info("=" * 100)
+ logger.info(log_str)
+ logger.info("=" * 100)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..f574ccabda2c4a0b0b3535945ccdb8044841bd16
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/README.md
@@ -0,0 +1,334 @@
+
+
+# Sequence-to-Sequence Training and Evaluation
+
+This directory contains examples for finetuning and evaluating transformers on summarization and translation tasks.
+For deprecated `bertabs` instructions, see [`bertabs/README.md`](https://github.com/huggingface/transformers/blob/main/examples/research_projects/bertabs/README.md).
+
+### Supported Architectures
+
+- `BartForConditionalGeneration`
+- `MarianMTModel`
+- `PegasusForConditionalGeneration`
+- `MBartForConditionalGeneration`
+- `FSMTForConditionalGeneration`
+- `T5ForConditionalGeneration`
+
+### Download the Datasets
+
+#### XSUM
+
+```bash
+cd examples/legacy/seq2seq
+wget https://cdn-datasets.huggingface.co/summarization/xsum.tar.gz
+tar -xzvf xsum.tar.gz
+export XSUM_DIR=${PWD}/xsum
+```
+this should make a directory called `xsum/` with files like `test.source`.
+To use your own data, copy that files format. Each article to be summarized is on its own line.
+
+#### CNN/DailyMail
+
+```bash
+cd examples/legacy/seq2seq
+wget https://cdn-datasets.huggingface.co/summarization/cnn_dm_v2.tgz
+tar -xzvf cnn_dm_v2.tgz # empty lines removed
+mv cnn_cln cnn_dm
+export CNN_DIR=${PWD}/cnn_dm
+```
+this should make a directory called `cnn_dm/` with 6 files.
+
+#### WMT16 English-Romanian Translation Data
+
+download with this command:
+```bash
+wget https://cdn-datasets.huggingface.co/translation/wmt_en_ro.tar.gz
+tar -xzvf wmt_en_ro.tar.gz
+export ENRO_DIR=${PWD}/wmt_en_ro
+```
+this should make a directory called `wmt_en_ro/` with 6 files.
+
+#### WMT English-German
+
+```bash
+wget https://cdn-datasets.huggingface.co/translation/wmt_en_de.tgz
+tar -xzvf wmt_en_de.tgz
+export DATA_DIR=${PWD}/wmt_en_de
+```
+
+#### FSMT datasets (wmt)
+
+Refer to the scripts starting with `eval_` under:
+https://github.com/huggingface/transformers/tree/main/scripts/fsmt
+
+#### Pegasus (multiple datasets)
+
+Multiple eval datasets are available for download from:
+https://github.com/stas00/porting/tree/master/datasets/pegasus
+
+
+#### Your Data
+
+If you are using your own data, it must be formatted as one directory with 6 files:
+```
+train.source
+train.target
+val.source
+val.target
+test.source
+test.target
+```
+The `.source` files are the input, the `.target` files are the desired output.
+
+### Potential issues
+
+- native AMP (`--fp16` and no apex) may lead to a huge memory leak and require 10x gpu memory. This has been fixed in pytorch-nightly and the minimal official version to have this fix will be pytorch-1.7.1. Until then if you have to use mixed precision please use AMP only with pytorch-nightly or NVIDIA's apex. Reference: https://github.com/huggingface/transformers/issues/8403
+
+
+### Tips and Tricks
+
+General Tips:
+- since you need to run from `examples/legacy/seq2seq`, and likely need to modify code, the easiest workflow is fork transformers, clone your fork, and run `pip install -e .` before you get started.
+- try `--freeze_encoder` or `--freeze_embeds` for faster training/larger batch size. (3hr per epoch with bs=8, see the "xsum_shared_task" command below)
+- `fp16_opt_level=O1` (the default works best).
+- In addition to the pytorch-lightning .ckpt checkpoint, a transformers checkpoint will be saved.
+Load it with `BartForConditionalGeneration.from_pretrained(f'{output_dir}/best_tfmr)`.
+- At the moment, `--do_predict` does not work in a multi-gpu setting. You need to use `evaluate_checkpoint` or the `run_eval.py` code.
+- This warning can be safely ignored:
+ > "Some weights of BartForConditionalGeneration were not initialized from the model checkpoint at facebook/bart-large-xsum and are newly initialized: ['final_logits_bias']"
+- Both finetuning and eval are 30% faster with `--fp16`. For that you need to [install apex](https://github.com/NVIDIA/apex#quick-start).
+- Read scripts before you run them!
+
+Summarization Tips:
+- (summ) 1 epoch at batch size 1 for bart-large takes 24 hours and requires 13GB GPU RAM with fp16 on an NVIDIA-V100.
+- If you want to run experiments on improving the summarization finetuning process, try the XSUM Shared Task (below). It's faster to train than CNNDM because the summaries are shorter.
+- For CNN/DailyMail, the default `val_max_target_length` and `test_max_target_length` will truncate the ground truth labels, resulting in slightly higher rouge scores. To get accurate rouge scores, you should rerun calculate_rouge on the `{output_dir}/test_generations.txt` file saved by `trainer.test()`
+- `--max_target_length=60 --val_max_target_length=60 --test_max_target_length=100 ` is a reasonable setting for XSUM.
+- `wandb` can be used by specifying `--logger_name wandb`. It is useful for reproducibility. Specify the environment variable `WANDB_PROJECT='hf_xsum'` to do the XSUM shared task.
+- If you are finetuning on your own dataset, start from `distilbart-cnn-12-6` if you want long summaries and `distilbart-xsum-12-6` if you want short summaries.
+(It rarely makes sense to start from `bart-large` unless you are a researching finetuning methods).
+
+**Update 2018-07-18**
+Datasets: `LegacySeq2SeqDataset` will be used for all tokenizers without a `prepare_seq2seq_batch` method. Otherwise, `Seq2SeqDataset` will be used.
+Future work/help wanted: A new dataset to support multilingual tasks.
+
+
+### Fine-tuning using Seq2SeqTrainer
+To use `Seq2SeqTrainer` for fine-tuning you should use the `finetune_trainer.py` script. It subclasses `Trainer` to extend it for seq2seq training. Except the `Trainer`-related `TrainingArguments`, it shares the same argument names as that of `finetune.py` file. One notable difference is that calculating generative metrics (BLEU, ROUGE) is optional and is controlled using the `--predict_with_generate` argument.
+
+With PyTorch 1.6+ it'll automatically use `native AMP` when `--fp16` is set.
+
+To see all the possible command line options, run:
+
+```bash
+python finetune_trainer.py --help
+```
+
+For multi-gpu training use `torch.distributed.launch`, e.g. with 2 gpus:
+```bash
+torchrun --nproc_per_node=2 finetune_trainer.py ...
+```
+
+**At the moment, `Seq2SeqTrainer` does not support *with teacher* distillation.**
+
+All `Seq2SeqTrainer`-based fine-tuning scripts are included in the `builtin_trainer` directory.
+
+#### TPU Training
+`Seq2SeqTrainer` supports TPU training with few caveats
+1. As `generate` method does not work on TPU at the moment, `predict_with_generate` cannot be used. You should use `--prediction_loss_only` to only calculate loss, and do not set `--do_predict` and `--predict_with_generate`.
+2. All sequences should be padded to be of equal length to avoid extremely slow training. (`finetune_trainer.py` does this automatically when running on TPU.)
+
+We provide a very simple launcher script named `xla_spawn.py` that lets you run our example scripts on multiple TPU cores without any boilerplate. Just pass a `--num_cores` flag to this script, then your regular training script with its arguments (this is similar to the `torch.distributed.launch` helper for `torch.distributed`).
+
+`builtin_trainer/finetune_tpu.sh` script provides minimal arguments needed for TPU training.
+
+The following command fine-tunes `sshleifer/student_marian_en_ro_6_3` on TPU V3-8 and should complete one epoch in ~5-6 mins.
+
+```bash
+./builtin_trainer/train_distil_marian_enro_tpu.sh
+```
+
+## Evaluation Commands
+
+To create summaries for each article in dataset, we use `run_eval.py`, here are a few commands that run eval for different tasks and models.
+If 'translation' is in your task name, the computed metric will be BLEU. Otherwise, ROUGE will be used.
+
+For t5, you need to specify --task translation_{src}_to_{tgt} as follows:
+```bash
+export DATA_DIR=wmt_en_ro
+./run_eval.py google-t5/t5-base \
+ $DATA_DIR/val.source t5_val_generations.txt \
+ --reference_path $DATA_DIR/val.target \
+ --score_path enro_bleu.json \
+ --task translation_en_to_ro \
+ --n_obs 100 \
+ --device cuda \
+ --fp16 \
+ --bs 32
+```
+
+This command works for MBART, although the BLEU score is suspiciously low.
+```bash
+export DATA_DIR=wmt_en_ro
+./run_eval.py facebook/mbart-large-en-ro $DATA_DIR/val.source mbart_val_generations.txt \
+ --reference_path $DATA_DIR/val.target \
+ --score_path enro_bleu.json \
+ --task translation \
+ --n_obs 100 \
+ --device cuda \
+ --fp16 \
+ --bs 32
+```
+
+Summarization (xsum will be very similar):
+```bash
+export DATA_DIR=cnn_dm
+./run_eval.py sshleifer/distilbart-cnn-12-6 $DATA_DIR/val.source dbart_val_generations.txt \
+ --reference_path $DATA_DIR/val.target \
+ --score_path cnn_rouge.json \
+ --task summarization \
+ --n_obs 100 \
+
+th 56 \
+ --fp16 \
+ --bs 32
+```
+
+### Multi-GPU Evaluation
+here is a command to run xsum evaluation on 8 GPUS. It is more than linearly faster than run_eval.py in some cases
+because it uses SortishSampler to minimize padding. You can also use it on 1 GPU. `data_dir` must have
+`{type_path}.source` and `{type_path}.target`. Run `./run_distributed_eval.py --help` for all clargs.
+
+```bash
+torchrun --nproc_per_node=8 run_distributed_eval.py \
+ --model_name sshleifer/distilbart-large-xsum-12-3 \
+ --save_dir xsum_generations \
+ --data_dir xsum \
+ --fp16 # you can pass generate kwargs like num_beams here, just like run_eval.py
+```
+
+Contributions that implement this command for other distributed hardware setups are welcome!
+
+#### Single-GPU Eval: Tips and Tricks
+
+When using `run_eval.py`, the following features can be useful:
+
+* if you running the script multiple times and want to make it easier to track what arguments produced that output, use `--dump-args`. Along with the results it will also dump any custom params that were passed to the script. For example if you used: `--num_beams 8 --early_stopping true`, the output will be:
+ ```json
+ {'bleu': 26.887, 'n_obs': 10, 'runtime': 1, 'seconds_per_sample': 0.1, 'num_beams': 8, 'early_stopping': True}
+ ```
+
+ `--info` is an additional argument available for the same purpose of tracking the conditions of the experiment. It's useful to pass things that weren't in the argument list, e.g. a language pair `--info "lang:en-ru"`. But also if you pass `--info` without a value it will fallback to the current date/time string, e.g. `2020-09-13 18:44:43`.
+
+ If using `--dump-args --info`, the output will be:
+
+ ```json
+ {'bleu': 26.887, 'n_obs': 10, 'runtime': 1, 'seconds_per_sample': 0.1, 'num_beams': 8, 'early_stopping': True, 'info': '2020-09-13 18:44:43'}
+ ```
+
+ If using `--dump-args --info "pair:en-ru chkpt=best`, the output will be:
+
+ ```json
+ {'bleu': 26.887, 'n_obs': 10, 'runtime': 1, 'seconds_per_sample': 0.1, 'num_beams': 8, 'early_stopping': True, 'info': 'pair=en-ru chkpt=best'}
+ ```
+
+
+* if you need to perform a parametric search in order to find the best ones that lead to the highest BLEU score, let `run_eval_search.py` to do the searching for you.
+
+ The script accepts the exact same arguments as `run_eval.py`, plus an additional argument `--search`. The value of `--search` is parsed, reformatted and fed to ``run_eval.py`` as additional args.
+
+ The format for the `--search` value is a simple string with hparams and colon separated values to try, e.g.:
+ ```
+ --search "num_beams=5:10 length_penalty=0.8:1.0:1.2 early_stopping=true:false"
+ ```
+ which will generate `12` `(2*3*2)` searches for a product of each hparam. For example the example that was just used will invoke `run_eval.py` repeatedly with:
+
+ ```
+ --num_beams 5 --length_penalty 0.8 --early_stopping true
+ --num_beams 5 --length_penalty 0.8 --early_stopping false
+ [...]
+ --num_beams 10 --length_penalty 1.2 --early_stopping false
+ ```
+
+ On completion, this function prints a markdown table of the results sorted by the best BLEU score and the winning arguments.
+
+```
+bleu | num_beams | length_penalty | early_stopping
+----- | --------- | -------------- | --------------
+26.71 | 5 | 1.1 | 1
+26.66 | 5 | 0.9 | 1
+26.66 | 5 | 0.9 | 0
+26.41 | 5 | 1.1 | 0
+21.94 | 1 | 0.9 | 1
+21.94 | 1 | 0.9 | 0
+21.94 | 1 | 1.1 | 1
+21.94 | 1 | 1.1 | 0
+
+Best score args:
+stas/wmt19-en-ru data/en-ru/val.source data/en-ru/test_translations.txt --reference_path data/en-ru/val.target --score_path data/en-ru/test_bleu.json --bs 8 --task translation --num_beams 5 --length_penalty 1.1 --early_stopping True
+```
+
+If you pass `--info "some experiment-specific info"` it will get printed before the results table - this is useful for scripting and multiple runs, so one can tell the different sets of results from each other.
+
+
+### Contributing
+- follow the standard contributing guidelines and code of conduct.
+- add tests to `test_seq2seq_examples.py`
+- To run only the seq2seq tests, you must be in the root of the repository and run:
+```bash
+pytest examples/seq2seq/
+```
+
+### Converting pytorch-lightning checkpoints
+pytorch lightning ``-do_predict`` often fails, after you are done training, the best way to evaluate your model is to convert it.
+
+This should be done for you, with a file called `{save_dir}/best_tfmr`.
+
+If that file doesn't exist but you have a lightning `.ckpt` file, you can run
+```bash
+python convert_pl_checkpoint_to_hf.py PATH_TO_CKPT randomly_initialized_hf_model_path save_dir/best_tfmr
+```
+Then either `run_eval` or `run_distributed_eval` with `save_dir/best_tfmr` (see previous sections)
+
+
+# Experimental Features
+These features are harder to use and not always useful.
+
+### Dynamic Batch Size for MT
+`finetune.py` has a command line arg `--max_tokens_per_batch` that allows batches to be dynamically sized.
+This feature can only be used:
+- with fairseq installed
+- on 1 GPU
+- without sortish sampler
+- after calling `./save_len_file.py $tok $data_dir`
+
+For example,
+```bash
+./save_len_file.py Helsinki-NLP/opus-mt-en-ro wmt_en_ro
+./dynamic_bs_example.sh --max_tokens_per_batch=2000 --output_dir benchmark_dynamic_bs
+```
+splits `wmt_en_ro/train` into 11,197 uneven length batches and can finish 1 epoch in 8 minutes on a v100.
+
+For comparison,
+```bash
+./dynamic_bs_example.sh --sortish_sampler --train_batch_size 48
+```
+uses 12,723 batches of length 48 and takes slightly more time 9.5 minutes.
+
+The feature is still experimental, because:
++ we can make it much more robust if we have memory mapped/preprocessed datasets.
++ The speedup over sortish sampler is not that large at the moment.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/__init__.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..3cee09bb7f51087e92d778c4c9e27d76085d1b30
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/__init__.py
@@ -0,0 +1,5 @@
+import os
+import sys
+
+
+sys.path.insert(1, os.path.dirname(os.path.realpath(__file__)))
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/convert_model_to_fp16.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/convert_model_to_fp16.py
new file mode 100644
index 0000000000000000000000000000000000000000..7fffbde79df7b7a9b5a4e079e1f17a58586b31ad
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/convert_model_to_fp16.py
@@ -0,0 +1,36 @@
+#!/usr/bin/env python
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from typing import Union
+
+import fire
+import torch
+from tqdm import tqdm
+
+
+def convert(src_path: str, map_location: str = "cpu", save_path: Union[str, None] = None) -> None:
+ """Convert a pytorch_model.bin or model.pt file to torch.float16 for faster downloads, less disk space."""
+ state_dict = torch.load(src_path, map_location=map_location)
+ for k, v in tqdm(state_dict.items()):
+ if not isinstance(v, torch.Tensor):
+ raise TypeError("FP16 conversion only works on paths that are saved state dicts, like pytorch_model.bin")
+ state_dict[k] = v.half()
+ if save_path is None: # overwrite src_path
+ save_path = src_path
+ torch.save(state_dict, save_path)
+
+
+if __name__ == "__main__":
+ fire.Fire(convert)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/download_wmt.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/download_wmt.py
new file mode 100644
index 0000000000000000000000000000000000000000..c52c0c7b4faca44e92b16313677ce6e788c27299
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/download_wmt.py
@@ -0,0 +1,67 @@
+#!/usr/bin/env python
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from pathlib import Path
+
+import fire
+from tqdm import tqdm
+
+
+def download_wmt_dataset(src_lang="ro", tgt_lang="en", dataset="wmt16", save_dir=None) -> None:
+ """Download a dataset using the datasets package and save it to the format expected by finetune.py
+ Format of save_dir: train.source, train.target, val.source, val.target, test.source, test.target.
+
+ Args:
+ src_lang: source language
+ tgt_lang: target language
+ dataset: wmt16, wmt17, etc. wmt16 is a good start as it's small. To get the full list run `import datasets; print([d.id for d in datasets.list_datasets() if "wmt" in d.id])`
+ save_dir: , where to save the datasets, defaults to f'{dataset}-{src_lang}-{tgt_lang}'
+
+ Usage:
+ >>> download_wmt_dataset('ro', 'en', dataset='wmt16') # saves to wmt16-ro-en
+ """
+ try:
+ import datasets
+ except (ModuleNotFoundError, ImportError):
+ raise ImportError("run pip install datasets")
+ pair = f"{src_lang}-{tgt_lang}"
+ print(f"Converting {dataset}-{pair}")
+ ds = datasets.load_dataset(dataset, pair)
+ if save_dir is None:
+ save_dir = f"{dataset}-{pair}"
+ save_dir = Path(save_dir)
+ save_dir.mkdir(exist_ok=True)
+
+ for split in ds.keys():
+ print(f"Splitting {split} with {ds[split].num_rows} records")
+
+ # to save to val.source, val.target like summary datasets
+ fn = "val" if split == "validation" else split
+ src_path = save_dir.joinpath(f"{fn}.source")
+ tgt_path = save_dir.joinpath(f"{fn}.target")
+ src_fp = src_path.open("w+")
+ tgt_fp = tgt_path.open("w+")
+
+ # reader is the bottleneck so writing one record at a time doesn't slow things down
+ for x in tqdm(ds[split]):
+ ex = x["translation"]
+ src_fp.write(ex[src_lang] + "\n")
+ tgt_fp.write(ex[tgt_lang] + "\n")
+
+ print(f"Saved {dataset} dataset to {save_dir}")
+
+
+if __name__ == "__main__":
+ fire.Fire(download_wmt_dataset)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/finetune.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/finetune.sh
new file mode 100644
index 0000000000000000000000000000000000000000..60023df7bad6aedba86987650c3d730aeb1ac229
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/finetune.sh
@@ -0,0 +1,24 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+# the proper usage is documented in the README, you need to specify data_dir, output_dir and model_name_or_path
+# run ./finetune.sh --help to see all the possible options
+python finetune_trainer.py \
+ --learning_rate=3e-5 \
+ --fp16 \
+ --do_train --do_eval --do_predict \
+ --eval_strategy steps \
+ --predict_with_generate \
+ --n_val 1000 \
+ "$@"
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/finetune_tpu.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/finetune_tpu.sh
new file mode 100644
index 0000000000000000000000000000000000000000..ef72b0953b440b88e86aee93d5aeb9ca0a864f16
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/finetune_tpu.sh
@@ -0,0 +1,26 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+export TPU_NUM_CORES=8
+
+# the proper usage is documented in the README, you need to specify data_dir, output_dir and model_name_or_path
+# run ./finetune_tpu.sh --help to see all the possible options
+python xla_spawn.py --num_cores $TPU_NUM_CORES \
+ finetune_trainer.py \
+ --learning_rate=3e-5 \
+ --do_train --do_eval \
+ --eval_strategy steps \
+ --prediction_loss_only \
+ --n_val 1000 \
+ "$@"
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/finetune_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/finetune_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..5ede86ee082265220a1a5453919467a9d3cba815
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/finetune_trainer.py
@@ -0,0 +1,375 @@
+#!/usr/bin/env python
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from typing import Optional
+
+from seq2seq_trainer import Seq2SeqTrainer
+from seq2seq_training_args import Seq2SeqTrainingArguments
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForSeq2SeqLM,
+ AutoTokenizer,
+ HfArgumentParser,
+ MBartTokenizer,
+ MBartTokenizerFast,
+ set_seed,
+)
+from transformers.trainer_utils import EvaluationStrategy, is_main_process
+from transformers.training_args import ParallelMode
+from utils import (
+ Seq2SeqDataCollator,
+ Seq2SeqDataset,
+ assert_all_frozen,
+ build_compute_metrics_fn,
+ check_output_dir,
+ freeze_embeds,
+ freeze_params,
+ lmap,
+ save_json,
+ use_task_specific_params,
+ write_txt_file,
+)
+
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+ freeze_encoder: bool = field(default=False, metadata={"help": "Whether tp freeze the encoder."})
+ freeze_embeds: bool = field(default=False, metadata={"help": "Whether to freeze the embeddings."})
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ data_dir: str = field(
+ metadata={"help": "The input data dir. Should contain the .tsv files (or other data files) for the task."}
+ )
+ task: Optional[str] = field(
+ default="summarization",
+ metadata={"help": "Task name, summarization (or summarization_{dataset} for pegasus) or translation"},
+ )
+ max_source_length: Optional[int] = field(
+ default=1024,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ max_target_length: Optional[int] = field(
+ default=128,
+ metadata={
+ "help": (
+ "The maximum total sequence length for target text after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ val_max_target_length: Optional[int] = field(
+ default=142,
+ metadata={
+ "help": (
+ "The maximum total sequence length for validation target text after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded. "
+ "This argument is also used to override the ``max_length`` param of ``model.generate``, which is used "
+ "during ``evaluate`` and ``predict``."
+ )
+ },
+ )
+ test_max_target_length: Optional[int] = field(
+ default=142,
+ metadata={
+ "help": (
+ "The maximum total sequence length for test target text after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ n_train: Optional[int] = field(default=-1, metadata={"help": "# training examples. -1 means use all."})
+ n_val: Optional[int] = field(default=-1, metadata={"help": "# validation examples. -1 means use all."})
+ n_test: Optional[int] = field(default=-1, metadata={"help": "# test examples. -1 means use all."})
+ src_lang: Optional[str] = field(default=None, metadata={"help": "Source language id for translation."})
+ tgt_lang: Optional[str] = field(default=None, metadata={"help": "Target language id for translation."})
+ eval_beams: Optional[int] = field(default=None, metadata={"help": "# num_beams to use for evaluation."})
+ ignore_pad_token_for_loss: bool = field(
+ default=True,
+ metadata={"help": "If only pad tokens should be ignored. This assumes that `config.pad_token_id` is defined."},
+ )
+
+
+def handle_metrics(split, metrics, output_dir):
+ """
+ Log and save metrics
+
+ Args:
+ - split: one of train, val, test
+ - metrics: metrics dict
+ - output_dir: where to save the metrics
+ """
+
+ logger.info(f"***** {split} metrics *****")
+ for key in sorted(metrics.keys()):
+ logger.info(f" {key} = {metrics[key]}")
+ save_json(metrics, os.path.join(output_dir, f"{split}_results.json"))
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, Seq2SeqTrainingArguments))
+
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ check_output_dir(training_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO if training_args.local_rank in [-1, 0] else logging.WARN,
+ )
+ logger.warning(
+ "Process rank: %s, device: %s, n_gpu: %s, distributed training: %s, 16-bits training: %s",
+ training_args.local_rank,
+ training_args.device,
+ training_args.n_gpu,
+ bool(training_args.parallel_mode == ParallelMode.DISTRIBUTED),
+ training_args.fp16,
+ )
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ if is_main_process(training_args.local_rank):
+ transformers.utils.logging.set_verbosity_info()
+ logger.info("Training/evaluation parameters %s", training_args)
+
+ # Set seed
+ set_seed(training_args.seed)
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ )
+
+ extra_model_params = ("encoder_layerdrop", "decoder_layerdrop", "dropout", "attention_dropout")
+ for p in extra_model_params:
+ if getattr(training_args, p, None):
+ assert hasattr(config, p), f"({config.__class__.__name__}) doesn't have a `{p}` attribute"
+ setattr(config, p, getattr(training_args, p))
+
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ )
+ model = AutoModelForSeq2SeqLM.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=".ckpt" in model_args.model_name_or_path,
+ config=config,
+ cache_dir=model_args.cache_dir,
+ )
+
+ # use task specific params
+ use_task_specific_params(model, data_args.task)
+
+ # set num_beams for evaluation
+ if data_args.eval_beams is None:
+ data_args.eval_beams = model.config.num_beams
+
+ # set decoder_start_token_id for MBart
+ if model.config.decoder_start_token_id is None and isinstance(tokenizer, (MBartTokenizer, MBartTokenizerFast)):
+ assert (
+ data_args.tgt_lang is not None and data_args.src_lang is not None
+ ), "mBart requires --tgt_lang and --src_lang"
+ if isinstance(tokenizer, MBartTokenizer):
+ model.config.decoder_start_token_id = tokenizer.lang_code_to_id[data_args.tgt_lang]
+ else:
+ model.config.decoder_start_token_id = tokenizer.convert_tokens_to_ids(data_args.tgt_lang)
+
+ if model_args.freeze_embeds:
+ freeze_embeds(model)
+ if model_args.freeze_encoder:
+ freeze_params(model.get_encoder())
+ assert_all_frozen(model.get_encoder())
+
+ dataset_class = Seq2SeqDataset
+
+ # Get datasets
+ train_dataset = (
+ dataset_class(
+ tokenizer,
+ type_path="train",
+ data_dir=data_args.data_dir,
+ n_obs=data_args.n_train,
+ max_target_length=data_args.max_target_length,
+ max_source_length=data_args.max_source_length,
+ prefix=model.config.prefix or "",
+ )
+ if training_args.do_train
+ else None
+ )
+ eval_dataset = (
+ dataset_class(
+ tokenizer,
+ type_path="val",
+ data_dir=data_args.data_dir,
+ n_obs=data_args.n_val,
+ max_target_length=data_args.val_max_target_length,
+ max_source_length=data_args.max_source_length,
+ prefix=model.config.prefix or "",
+ )
+ if training_args.do_eval or training_args.eval_strategy != EvaluationStrategy.NO
+ else None
+ )
+ test_dataset = (
+ dataset_class(
+ tokenizer,
+ type_path="test",
+ data_dir=data_args.data_dir,
+ n_obs=data_args.n_test,
+ max_target_length=data_args.test_max_target_length,
+ max_source_length=data_args.max_source_length,
+ prefix=model.config.prefix or "",
+ )
+ if training_args.do_predict
+ else None
+ )
+
+ # Initialize our Trainer
+ compute_metrics_fn = (
+ build_compute_metrics_fn(data_args.task, tokenizer) if training_args.predict_with_generate else None
+ )
+ trainer = Seq2SeqTrainer(
+ model=model,
+ args=training_args,
+ data_args=data_args,
+ train_dataset=train_dataset,
+ eval_dataset=eval_dataset,
+ data_collator=Seq2SeqDataCollator(
+ tokenizer, data_args, model.config.decoder_start_token_id, training_args.tpu_num_cores
+ ),
+ compute_metrics=compute_metrics_fn,
+ processing_class=tokenizer,
+ )
+
+ all_metrics = {}
+ # Training
+ if training_args.do_train:
+ logger.info("*** Train ***")
+
+ train_result = trainer.train(
+ model_path=model_args.model_name_or_path if os.path.isdir(model_args.model_name_or_path) else None
+ )
+ metrics = train_result.metrics
+ metrics["train_n_objs"] = data_args.n_train
+
+ trainer.save_model() # this also saves the tokenizer
+
+ if trainer.is_world_process_zero():
+ handle_metrics("train", metrics, training_args.output_dir)
+ all_metrics.update(metrics)
+
+ # Need to save the state, since Trainer.save_model saves only the tokenizer with the model
+ trainer.state.save_to_json(os.path.join(training_args.output_dir, "trainer_state.json"))
+
+ # For convenience, we also re-save the tokenizer to the same directory,
+ # so that you can share your model easily on huggingface.co/models =)
+ tokenizer.save_pretrained(training_args.output_dir)
+
+ # Evaluation
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+
+ metrics = trainer.evaluate(metric_key_prefix="val")
+ metrics["val_n_objs"] = data_args.n_val
+ metrics["val_loss"] = round(metrics["val_loss"], 4)
+
+ if trainer.is_world_process_zero():
+ handle_metrics("val", metrics, training_args.output_dir)
+ all_metrics.update(metrics)
+
+ if training_args.do_predict:
+ logger.info("*** Predict ***")
+
+ test_output = trainer.predict(test_dataset=test_dataset, metric_key_prefix="test")
+ metrics = test_output.metrics
+ metrics["test_n_objs"] = data_args.n_test
+
+ if trainer.is_world_process_zero():
+ metrics["test_loss"] = round(metrics["test_loss"], 4)
+ handle_metrics("test", metrics, training_args.output_dir)
+ all_metrics.update(metrics)
+
+ if training_args.predict_with_generate:
+ test_preds = tokenizer.batch_decode(
+ test_output.predictions, skip_special_tokens=True, clean_up_tokenization_spaces=True
+ )
+ test_preds = lmap(str.strip, test_preds)
+ write_txt_file(test_preds, os.path.join(training_args.output_dir, "test_generations.txt"))
+
+ if trainer.is_world_process_zero():
+ save_json(all_metrics, os.path.join(training_args.output_dir, "all_results.json"))
+
+ return all_metrics
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/minify_dataset.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/minify_dataset.py
new file mode 100644
index 0000000000000000000000000000000000000000..e6095cecc8e99f231b80a3779b594cc29fd0ddda
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/minify_dataset.py
@@ -0,0 +1,34 @@
+#!/usr/bin/env python
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from pathlib import Path
+
+import fire
+
+
+def minify(src_dir: str, dest_dir: str, n: int):
+ """Write first n lines of each file f in src_dir to dest_dir/f"""
+ src_dir = Path(src_dir)
+ dest_dir = Path(dest_dir)
+ dest_dir.mkdir(exist_ok=True)
+ for path in src_dir.iterdir():
+ new = [x.rstrip() for x in list(path.open().readlines())][:n]
+ dest_path = dest_dir.joinpath(path.name)
+ print(dest_path)
+ dest_path.open("w").write("\n".join(new))
+
+
+if __name__ == "__main__":
+ fire.Fire(minify)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_calculate_rouge.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_calculate_rouge.py
new file mode 100644
index 0000000000000000000000000000000000000000..6cc15e02552be105a28ac93d177b09a7f9bc92a2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_calculate_rouge.py
@@ -0,0 +1,109 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from collections import defaultdict
+from pathlib import Path
+
+import pandas as pd
+from rouge_cli import calculate_rouge_path
+
+from utils import calculate_rouge
+
+
+PRED = [
+ 'Prosecutor: "No videos were used in the crash investigation" German papers say they saw a cell phone video of the'
+ ' final seconds on board Flight 9525. The Germanwings co-pilot says he had a "previous episode of severe'
+ " depression\" German airline confirms it knew of Andreas Lubitz's depression years before he took control.",
+ "The Palestinian Authority officially becomes the 123rd member of the International Criminal Court. The formal"
+ " accession was marked with a ceremony at The Hague, in the Netherlands. The Palestinians signed the ICC's"
+ " founding Rome Statute in January. Israel and the United States opposed the Palestinians' efforts to join the"
+ " body.",
+ "Amnesty International releases its annual report on the death penalty. The report catalogs the use of"
+ " state-sanctioned killing as a punitive measure across the globe. At least 607 people were executed around the"
+ " world in 2014, compared to 778 in 2013. The U.S. remains one of the worst offenders for imposing capital"
+ " punishment.",
+]
+
+TGT = [
+ 'Marseille prosecutor says "so far no videos were used in the crash investigation" despite media reports .'
+ ' Journalists at Bild and Paris Match are "very confident" the video clip is real, an editor says . Andreas Lubitz'
+ " had informed his Lufthansa training school of an episode of severe depression, airline says .",
+ "Membership gives the ICC jurisdiction over alleged crimes committed in Palestinian territories since last June ."
+ " Israel and the United States opposed the move, which could open the door to war crimes investigations against"
+ " Israelis .",
+ "Amnesty's annual death penalty report catalogs encouraging signs, but setbacks in numbers of those sentenced to"
+ " death . Organization claims that governments around the world are using the threat of terrorism to advance"
+ " executions . The number of executions worldwide has gone down by almost 22% compared with 2013, but death"
+ " sentences up by 28% .",
+]
+
+
+def test_disaggregated_scores_are_determinstic():
+ no_aggregation = calculate_rouge(PRED, TGT, bootstrap_aggregation=False, rouge_keys=["rouge2", "rougeL"])
+ assert isinstance(no_aggregation, defaultdict)
+ no_aggregation_just_r2 = calculate_rouge(PRED, TGT, bootstrap_aggregation=False, rouge_keys=["rouge2"])
+ assert (
+ pd.DataFrame(no_aggregation["rouge2"]).fmeasure.mean()
+ == pd.DataFrame(no_aggregation_just_r2["rouge2"]).fmeasure.mean()
+ )
+
+
+def test_newline_cnn_improvement():
+ k = "rougeLsum"
+ score = calculate_rouge(PRED, TGT, newline_sep=True, rouge_keys=[k])[k]
+ score_no_sep = calculate_rouge(PRED, TGT, newline_sep=False, rouge_keys=[k])[k]
+ assert score > score_no_sep
+
+
+def test_newline_irrelevant_for_other_metrics():
+ k = ["rouge1", "rouge2", "rougeL"]
+ score_sep = calculate_rouge(PRED, TGT, newline_sep=True, rouge_keys=k)
+ score_no_sep = calculate_rouge(PRED, TGT, newline_sep=False, rouge_keys=k)
+ assert score_sep == score_no_sep
+
+
+def test_single_sent_scores_dont_depend_on_newline_sep():
+ pred = [
+ "Her older sister, Margot Frank, died in 1945, a month earlier than previously thought.",
+ 'Marseille prosecutor says "so far no videos were used in the crash investigation" despite media reports .',
+ ]
+ tgt = [
+ "Margot Frank, died in 1945, a month earlier than previously thought.",
+ 'Prosecutor: "No videos were used in the crash investigation" German papers say they saw a cell phone video of'
+ " the final seconds on board Flight 9525.",
+ ]
+ assert calculate_rouge(pred, tgt, newline_sep=True) == calculate_rouge(pred, tgt, newline_sep=False)
+
+
+def test_pegasus_newline():
+ pred = [
+ """" "a person who has such a video needs to immediately give it to the investigators," prosecutor says . "it is a very disturbing scene," editor-in-chief of bild online tells "erin burnett: outfront" """
+ ]
+ tgt = [
+ """ Marseille prosecutor says "so far no videos were used in the crash investigation" despite media reports . Journalists at Bild and Paris Match are "very confident" the video clip is real, an editor says . Andreas Lubitz had informed his Lufthansa training school of an episode of severe depression, airline says ."""
+ ]
+
+ prev_score = calculate_rouge(pred, tgt, rouge_keys=["rougeLsum"], newline_sep=False)["rougeLsum"]
+ new_score = calculate_rouge(pred, tgt, rouge_keys=["rougeLsum"])["rougeLsum"]
+ assert new_score > prev_score
+
+
+def test_rouge_cli():
+ data_dir = Path("examples/seq2seq/test_data/wmt_en_ro")
+ metrics = calculate_rouge_path(data_dir.joinpath("test.source"), data_dir.joinpath("test.target"))
+ assert isinstance(metrics, dict)
+ metrics_default_dict = calculate_rouge_path(
+ data_dir.joinpath("test.source"), data_dir.joinpath("test.target"), bootstrap_aggregation=False
+ )
+ assert isinstance(metrics_default_dict, defaultdict)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_datasets.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_datasets.py
new file mode 100644
index 0000000000000000000000000000000000000000..be108f7645f8a96e18a84430cee1e846a263a530
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_datasets.py
@@ -0,0 +1,247 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import os
+from pathlib import Path
+
+import numpy as np
+import pytest
+from pack_dataset import pack_data_dir
+from parameterized import parameterized
+from save_len_file import save_len_file
+from torch.utils.data import DataLoader
+
+from transformers import AutoTokenizer
+from transformers.models.mbart.modeling_mbart import shift_tokens_right
+from transformers.testing_utils import TestCasePlus, slow
+from utils import FAIRSEQ_AVAILABLE, DistributedSortishSampler, LegacySeq2SeqDataset, Seq2SeqDataset
+
+
+BERT_BASE_CASED = "google-bert/bert-base-cased"
+PEGASUS_XSUM = "google/pegasus-xsum"
+ARTICLES = [" Sam ate lunch today.", "Sams lunch ingredients."]
+SUMMARIES = ["A very interesting story about what I ate for lunch.", "Avocado, celery, turkey, coffee"]
+T5_TINY = "patrickvonplaten/t5-tiny-random"
+BART_TINY = "sshleifer/bart-tiny-random"
+MBART_TINY = "sshleifer/tiny-mbart"
+MARIAN_TINY = "sshleifer/tiny-marian-en-de"
+
+
+def _dump_articles(path: Path, articles: list):
+ content = "\n".join(articles)
+ Path(path).open("w").writelines(content)
+
+
+def make_test_data_dir(tmp_dir):
+ for split in ["train", "val", "test"]:
+ _dump_articles(os.path.join(tmp_dir, f"{split}.source"), ARTICLES)
+ _dump_articles(os.path.join(tmp_dir, f"{split}.target"), SUMMARIES)
+ return tmp_dir
+
+
+class TestAll(TestCasePlus):
+ @parameterized.expand(
+ [
+ MBART_TINY,
+ MARIAN_TINY,
+ T5_TINY,
+ BART_TINY,
+ PEGASUS_XSUM,
+ ],
+ )
+ @slow
+ def test_seq2seq_dataset_truncation(self, tok_name):
+ tokenizer = AutoTokenizer.from_pretrained(tok_name)
+ tmp_dir = make_test_data_dir(tmp_dir=self.get_auto_remove_tmp_dir())
+ max_len_source = max(len(tokenizer.encode(a)) for a in ARTICLES)
+ max_len_target = max(len(tokenizer.encode(a)) for a in SUMMARIES)
+ max_src_len = 4
+ max_tgt_len = 8
+ assert max_len_target > max_src_len # Will be truncated
+ assert max_len_source > max_src_len # Will be truncated
+ src_lang, tgt_lang = "ro_RO", "de_DE" # ignored for all but mbart, but never causes error.
+ train_dataset = Seq2SeqDataset(
+ tokenizer,
+ data_dir=tmp_dir,
+ type_path="train",
+ max_source_length=max_src_len,
+ max_target_length=max_tgt_len, # ignored
+ src_lang=src_lang,
+ tgt_lang=tgt_lang,
+ )
+ dataloader = DataLoader(train_dataset, batch_size=2, collate_fn=train_dataset.collate_fn)
+ for batch in dataloader:
+ assert isinstance(batch, dict)
+ assert batch["attention_mask"].shape == batch["input_ids"].shape
+ # show that articles were trimmed.
+ assert batch["input_ids"].shape[1] == max_src_len
+ # show that targets are the same len
+ assert batch["labels"].shape[1] == max_tgt_len
+ if tok_name != MBART_TINY:
+ continue
+ # check language codes in correct place
+ batch["decoder_input_ids"] = shift_tokens_right(batch["labels"], tokenizer.pad_token_id)
+ assert batch["decoder_input_ids"][0, 0].item() == tokenizer.lang_code_to_id[tgt_lang]
+ assert batch["decoder_input_ids"][0, -1].item() == tokenizer.eos_token_id
+ assert batch["input_ids"][0, -2].item() == tokenizer.eos_token_id
+ assert batch["input_ids"][0, -1].item() == tokenizer.lang_code_to_id[src_lang]
+
+ break # No need to test every batch
+
+ @parameterized.expand([BART_TINY, BERT_BASE_CASED])
+ def test_legacy_dataset_truncation(self, tok):
+ tokenizer = AutoTokenizer.from_pretrained(tok)
+ tmp_dir = make_test_data_dir(tmp_dir=self.get_auto_remove_tmp_dir())
+ max_len_source = max(len(tokenizer.encode(a)) for a in ARTICLES)
+ max_len_target = max(len(tokenizer.encode(a)) for a in SUMMARIES)
+ trunc_target = 4
+ train_dataset = LegacySeq2SeqDataset(
+ tokenizer,
+ data_dir=tmp_dir,
+ type_path="train",
+ max_source_length=20,
+ max_target_length=trunc_target,
+ )
+ dataloader = DataLoader(train_dataset, batch_size=2, collate_fn=train_dataset.collate_fn)
+ for batch in dataloader:
+ assert batch["attention_mask"].shape == batch["input_ids"].shape
+ # show that articles were trimmed.
+ assert batch["input_ids"].shape[1] == max_len_source
+ assert 20 >= batch["input_ids"].shape[1] # trimmed significantly
+ # show that targets were truncated
+ assert batch["labels"].shape[1] == trunc_target # Truncated
+ assert max_len_target > trunc_target # Truncated
+ break # No need to test every batch
+
+ def test_pack_dataset(self):
+ tokenizer = AutoTokenizer.from_pretrained("facebook/mbart-large-cc25")
+
+ tmp_dir = Path(make_test_data_dir(tmp_dir=self.get_auto_remove_tmp_dir()))
+ orig_examples = tmp_dir.joinpath("train.source").open().readlines()
+ save_dir = Path(make_test_data_dir(tmp_dir=self.get_auto_remove_tmp_dir()))
+ pack_data_dir(tokenizer, tmp_dir, 128, save_dir)
+ orig_paths = {x.name for x in tmp_dir.iterdir()}
+ new_paths = {x.name for x in save_dir.iterdir()}
+ packed_examples = save_dir.joinpath("train.source").open().readlines()
+ # orig: [' Sam ate lunch today.\n', 'Sams lunch ingredients.']
+ # desired_packed: [' Sam ate lunch today.\n Sams lunch ingredients.']
+ assert len(packed_examples) < len(orig_examples)
+ assert len(packed_examples) == 1
+ assert len(packed_examples[0]) == sum(len(x) for x in orig_examples)
+ assert orig_paths == new_paths
+
+ @pytest.mark.skipif(not FAIRSEQ_AVAILABLE, reason="This test requires fairseq")
+ def test_dynamic_batch_size(self):
+ if not FAIRSEQ_AVAILABLE:
+ return
+ ds, max_tokens, tokenizer = self._get_dataset(max_len=64)
+ required_batch_size_multiple = 64
+ batch_sampler = ds.make_dynamic_sampler(max_tokens, required_batch_size_multiple=required_batch_size_multiple)
+ batch_sizes = [len(x) for x in batch_sampler]
+ assert len(set(batch_sizes)) > 1 # it's not dynamic batch size if every batch is the same length
+ assert sum(batch_sizes) == len(ds) # no dropped or added examples
+ data_loader = DataLoader(ds, batch_sampler=batch_sampler, collate_fn=ds.collate_fn, num_workers=2)
+ failures = []
+ num_src_per_batch = []
+ for batch in data_loader:
+ src_shape = batch["input_ids"].shape
+ bs = src_shape[0]
+ assert bs % required_batch_size_multiple == 0 or bs < required_batch_size_multiple
+ num_src_tokens = np.product(batch["input_ids"].shape)
+ num_src_per_batch.append(num_src_tokens)
+ if num_src_tokens > (max_tokens * 1.1):
+ failures.append(num_src_tokens)
+ assert num_src_per_batch[0] == max(num_src_per_batch)
+ if failures:
+ raise AssertionError(f"too many tokens in {len(failures)} batches")
+
+ def test_sortish_sampler_reduces_padding(self):
+ ds, _, tokenizer = self._get_dataset(max_len=512)
+ bs = 2
+ sortish_sampler = ds.make_sortish_sampler(bs, shuffle=False)
+
+ naive_dl = DataLoader(ds, batch_size=bs, collate_fn=ds.collate_fn, num_workers=2)
+ sortish_dl = DataLoader(ds, batch_size=bs, collate_fn=ds.collate_fn, num_workers=2, sampler=sortish_sampler)
+
+ pad = tokenizer.pad_token_id
+
+ def count_pad_tokens(data_loader, k="input_ids"):
+ return [batch[k].eq(pad).sum().item() for batch in data_loader]
+
+ assert sum(count_pad_tokens(sortish_dl, k="labels")) < sum(count_pad_tokens(naive_dl, k="labels"))
+ assert sum(count_pad_tokens(sortish_dl)) < sum(count_pad_tokens(naive_dl))
+ assert len(sortish_dl) == len(naive_dl)
+
+ def _get_dataset(self, n_obs=1000, max_len=128):
+ if os.getenv("USE_REAL_DATA", False):
+ data_dir = "examples/seq2seq/wmt_en_ro"
+ max_tokens = max_len * 2 * 64
+ if not Path(data_dir).joinpath("train.len").exists():
+ save_len_file(MARIAN_TINY, data_dir)
+ else:
+ data_dir = "examples/seq2seq/test_data/wmt_en_ro"
+ max_tokens = max_len * 4
+ save_len_file(MARIAN_TINY, data_dir)
+
+ tokenizer = AutoTokenizer.from_pretrained(MARIAN_TINY)
+ ds = Seq2SeqDataset(
+ tokenizer,
+ data_dir=data_dir,
+ type_path="train",
+ max_source_length=max_len,
+ max_target_length=max_len,
+ n_obs=n_obs,
+ )
+ return ds, max_tokens, tokenizer
+
+ def test_distributed_sortish_sampler_splits_indices_between_procs(self):
+ ds, max_tokens, tokenizer = self._get_dataset()
+ ids1 = set(DistributedSortishSampler(ds, 256, num_replicas=2, rank=0, add_extra_examples=False))
+ ids2 = set(DistributedSortishSampler(ds, 256, num_replicas=2, rank=1, add_extra_examples=False))
+ assert ids1.intersection(ids2) == set()
+
+ @parameterized.expand(
+ [
+ MBART_TINY,
+ MARIAN_TINY,
+ T5_TINY,
+ BART_TINY,
+ PEGASUS_XSUM,
+ ],
+ )
+ def test_dataset_kwargs(self, tok_name):
+ tokenizer = AutoTokenizer.from_pretrained(tok_name, use_fast=False)
+ if tok_name == MBART_TINY:
+ train_dataset = Seq2SeqDataset(
+ tokenizer,
+ data_dir=make_test_data_dir(tmp_dir=self.get_auto_remove_tmp_dir()),
+ type_path="train",
+ max_source_length=4,
+ max_target_length=8,
+ src_lang="EN",
+ tgt_lang="FR",
+ )
+ kwargs = train_dataset.dataset_kwargs
+ assert "src_lang" in kwargs and "tgt_lang" in kwargs
+ else:
+ train_dataset = Seq2SeqDataset(
+ tokenizer,
+ data_dir=make_test_data_dir(tmp_dir=self.get_auto_remove_tmp_dir()),
+ type_path="train",
+ max_source_length=4,
+ max_target_length=8,
+ )
+ kwargs = train_dataset.dataset_kwargs
+ assert "add_prefix_space" not in kwargs if tok_name != BART_TINY else "add_prefix_space" in kwargs
+ assert len(kwargs) == 1 if tok_name == BART_TINY else len(kwargs) == 0
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_fsmt_bleu_score.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_fsmt_bleu_score.py
new file mode 100644
index 0000000000000000000000000000000000000000..4aefeb388be6314df1835f1f15738e7029f47996
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_fsmt_bleu_score.py
@@ -0,0 +1,72 @@
+# coding=utf-8
+# Copyright 2020 Huggingface
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import io
+import json
+import unittest
+
+from parameterized import parameterized
+
+from transformers import FSMTForConditionalGeneration, FSMTTokenizer
+from transformers.testing_utils import get_tests_dir, require_torch, slow, torch_device
+from utils import calculate_bleu
+
+
+filename = get_tests_dir() + "/test_data/fsmt/fsmt_val_data.json"
+with io.open(filename, "r", encoding="utf-8") as f:
+ bleu_data = json.load(f)
+
+
+@require_torch
+class ModelEvalTester(unittest.TestCase):
+ def get_tokenizer(self, mname):
+ return FSMTTokenizer.from_pretrained(mname)
+
+ def get_model(self, mname):
+ model = FSMTForConditionalGeneration.from_pretrained(mname).to(torch_device)
+ if torch_device == "cuda":
+ model.half()
+ return model
+
+ @parameterized.expand(
+ [
+ ["en-ru", 26.0],
+ ["ru-en", 22.0],
+ ["en-de", 22.0],
+ ["de-en", 29.0],
+ ]
+ )
+ @slow
+ def test_bleu_scores(self, pair, min_bleu_score):
+ # note: this test is not testing the best performance since it only evals a small batch
+ # but it should be enough to detect a regression in the output quality
+ mname = f"facebook/wmt19-{pair}"
+ tokenizer = self.get_tokenizer(mname)
+ model = self.get_model(mname)
+
+ src_sentences = bleu_data[pair]["src"]
+ tgt_sentences = bleu_data[pair]["tgt"]
+
+ batch = tokenizer(src_sentences, return_tensors="pt", truncation=True, padding="longest").to(torch_device)
+ outputs = model.generate(
+ input_ids=batch.input_ids,
+ num_beams=8,
+ )
+ decoded_sentences = tokenizer.batch_decode(
+ outputs, skip_special_tokens=True, clean_up_tokenization_spaces=False
+ )
+ scores = calculate_bleu(decoded_sentences, tgt_sentences)
+ print(scores)
+ self.assertGreaterEqual(scores["bleu"], min_bleu_score)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_seq2seq_examples.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_seq2seq_examples.py
new file mode 100644
index 0000000000000000000000000000000000000000..864b97c7466a36a27eec3bea2e9aa28e9695f21f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_seq2seq_examples.py
@@ -0,0 +1,132 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import logging
+import os
+import sys
+from pathlib import Path
+from unittest.mock import patch
+
+from parameterized import parameterized
+from run_eval import run_generate
+from run_eval_search import run_search
+
+from transformers.testing_utils import CaptureStdout, TestCasePlus, slow
+from utils import ROUGE_KEYS
+
+
+logging.basicConfig(level=logging.DEBUG)
+logger = logging.getLogger()
+
+
+def _dump_articles(path: Path, articles: list):
+ content = "\n".join(articles)
+ Path(path).open("w").writelines(content)
+
+
+T5_TINY = "patrickvonplaten/t5-tiny-random"
+BART_TINY = "sshleifer/bart-tiny-random"
+MBART_TINY = "sshleifer/tiny-mbart"
+
+stream_handler = logging.StreamHandler(sys.stdout)
+logger.addHandler(stream_handler)
+logging.disable(logging.CRITICAL) # remove noisy download output from tracebacks
+
+
+class TestTheRest(TestCasePlus):
+ def run_eval_tester(self, model):
+ input_file_name = Path(self.get_auto_remove_tmp_dir()) / "utest_input.source"
+ output_file_name = input_file_name.parent / "utest_output.txt"
+ assert not output_file_name.exists()
+ articles = [" New York (CNN)When Liana Barrientos was 23 years old, she got married in Westchester County."]
+ _dump_articles(input_file_name, articles)
+
+ score_path = str(Path(self.get_auto_remove_tmp_dir()) / "scores.json")
+ task = "translation_en_to_de" if model == T5_TINY else "summarization"
+ testargs = f"""
+ run_eval_search.py
+ {model}
+ {input_file_name}
+ {output_file_name}
+ --score_path {score_path}
+ --task {task}
+ --num_beams 2
+ --length_penalty 2.0
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ run_generate()
+ assert Path(output_file_name).exists()
+ # os.remove(Path(output_file_name))
+
+ # test one model to quickly (no-@slow) catch simple problems and do an
+ # extensive testing of functionality with multiple models as @slow separately
+ def test_run_eval(self):
+ self.run_eval_tester(T5_TINY)
+
+ # any extra models should go into the list here - can be slow
+ @parameterized.expand([BART_TINY, MBART_TINY])
+ @slow
+ def test_run_eval_slow(self, model):
+ self.run_eval_tester(model)
+
+ # testing with 2 models to validate: 1. translation (t5) 2. summarization (mbart)
+ @parameterized.expand([T5_TINY, MBART_TINY])
+ @slow
+ def test_run_eval_search(self, model):
+ input_file_name = Path(self.get_auto_remove_tmp_dir()) / "utest_input.source"
+ output_file_name = input_file_name.parent / "utest_output.txt"
+ assert not output_file_name.exists()
+
+ text = {
+ "en": ["Machine learning is great, isn't it?", "I like to eat bananas", "Tomorrow is another great day!"],
+ "de": [
+ "Maschinelles Lernen ist großartig, oder?",
+ "Ich esse gerne Bananen",
+ "Morgen ist wieder ein toller Tag!",
+ ],
+ }
+
+ tmp_dir = Path(self.get_auto_remove_tmp_dir())
+ score_path = str(tmp_dir / "scores.json")
+ reference_path = str(tmp_dir / "val.target")
+ _dump_articles(input_file_name, text["en"])
+ _dump_articles(reference_path, text["de"])
+ task = "translation_en_to_de" if model == T5_TINY else "summarization"
+ testargs = f"""
+ run_eval_search.py
+ {model}
+ {str(input_file_name)}
+ {str(output_file_name)}
+ --score_path {score_path}
+ --reference_path {reference_path}
+ --task {task}
+ """.split()
+ testargs.extend(["--search", "num_beams=1:2 length_penalty=0.9:1.0"])
+
+ with patch.object(sys, "argv", testargs):
+ with CaptureStdout() as cs:
+ run_search()
+ expected_strings = [" num_beams | length_penalty", model, "Best score args"]
+ un_expected_strings = ["Info"]
+ if "translation" in task:
+ expected_strings.append("bleu")
+ else:
+ expected_strings.extend(ROUGE_KEYS)
+ for w in expected_strings:
+ assert w in cs.out
+ for w in un_expected_strings:
+ assert w not in cs.out
+ assert Path(output_file_name).exists()
+ os.remove(Path(output_file_name))
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_seq2seq_examples_multi_gpu.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_seq2seq_examples_multi_gpu.py
new file mode 100644
index 0000000000000000000000000000000000000000..6625f061b5660793a5a054acd4eab518622bf5f8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_seq2seq_examples_multi_gpu.py
@@ -0,0 +1,55 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+# as due to their complexity multi-gpu tests could impact other tests, and to aid debug we have those in a separate module.
+
+import os
+import sys
+
+from transformers.testing_utils import TestCasePlus, execute_subprocess_async, get_gpu_count, require_torch_gpu, slow
+
+from .utils import load_json
+
+
+class TestSummarizationDistillerMultiGPU(TestCasePlus):
+ @classmethod
+ def setUpClass(cls):
+ return cls
+
+ @slow
+ @require_torch_gpu
+ def test_distributed_eval(self):
+ output_dir = self.get_auto_remove_tmp_dir()
+ args = f"""
+ --model_name Helsinki-NLP/opus-mt-en-ro
+ --save_dir {output_dir}
+ --data_dir {self.test_file_dir_str}/test_data/wmt_en_ro
+ --num_beams 2
+ --task translation
+ """.split()
+
+ # we want this test to run even if there is only one GPU, but if there are more we use them all
+ n_gpu = get_gpu_count()
+ distributed_args = f"""
+ -m torch.distributed.launch
+ --nproc_per_node={n_gpu}
+ {self.test_file_dir}/run_distributed_eval.py
+ """.split()
+ cmd = [sys.executable] + distributed_args + args
+ execute_subprocess_async(cmd, env=self.get_env())
+
+ metrics_save_path = os.path.join(output_dir, "test_bleu.json")
+ metrics = load_json(metrics_save_path)
+ # print(metrics)
+ self.assertGreaterEqual(metrics["bleu"], 25)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_tatoeba_conversion.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_tatoeba_conversion.py
new file mode 100644
index 0000000000000000000000000000000000000000..b9733daf85e186b72eeb24d2b07347f10cea2586
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/old_test_tatoeba_conversion.py
@@ -0,0 +1,38 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import os
+import tempfile
+import unittest
+
+from transformers.models.marian.convert_marian_tatoeba_to_pytorch import DEFAULT_REPO, TatoebaConverter
+from transformers.testing_utils import slow
+from transformers.utils import cached_property
+
+
+@unittest.skipUnless(os.path.exists(DEFAULT_REPO), "Tatoeba directory does not exist.")
+class TatoebaConversionTester(unittest.TestCase):
+ @cached_property
+ def resolver(self):
+ tmp_dir = tempfile.mkdtemp()
+ return TatoebaConverter(save_dir=tmp_dir)
+
+ @slow
+ def test_resolver(self):
+ self.resolver.convert_models(["heb-eng"])
+
+ @slow
+ def test_model_card(self):
+ content, mmeta = self.resolver.write_model_card("opus-mt-he-en", dry_run=True)
+ assert mmeta["long_pair"] == "heb-eng"
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/pack_dataset.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/pack_dataset.py
new file mode 100644
index 0000000000000000000000000000000000000000..5c13c74f412df6b46f0b7020c83f9a6476e3f2df
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/pack_dataset.py
@@ -0,0 +1,87 @@
+#!/usr/bin/env python
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fill examples with bitext up to max_tokens without breaking up examples.
+[['I went', 'yo fui'],
+['to the store', 'a la tienda']
+]
+=> ['I went to the store', 'yo fui a la tienda']
+"""
+
+import argparse
+import shutil
+from pathlib import Path
+
+from tqdm import tqdm
+
+from transformers import AutoTokenizer
+
+
+def pack_examples(tok, src_examples, tgt_examples, max_tokens=1024):
+ finished_src, finished_tgt = [], []
+
+ sorted_examples = list(zip(src_examples, tgt_examples))
+ new_src, new_tgt = sorted_examples[0]
+
+ def is_too_big(strang):
+ return tok(strang, return_tensors="pt").input_ids.shape[1] > max_tokens
+
+ for src, tgt in tqdm(sorted_examples[1:]):
+ cand_src = new_src + " " + src
+ cand_tgt = new_tgt + " " + tgt
+ if is_too_big(cand_src) or is_too_big(cand_tgt): # cant fit, finalize example
+ finished_src.append(new_src)
+ finished_tgt.append(new_tgt)
+ new_src, new_tgt = src, tgt
+ else: # can fit, keep adding
+ new_src, new_tgt = cand_src, cand_tgt
+
+ # cleanup
+ if new_src:
+ assert new_tgt
+ finished_src.append(new_src)
+ finished_tgt.append(new_tgt)
+ return finished_src, finished_tgt
+
+
+def pack_data_dir(tok, data_dir: Path, max_tokens, save_path):
+ save_path = Path(save_path)
+ save_path.mkdir(exist_ok=True)
+ for split in ["train"]:
+ src_path, tgt_path = data_dir / f"{split}.source", data_dir / f"{split}.target"
+ src_docs = [x.rstrip() for x in Path(src_path).open().readlines()]
+ tgt_docs = [x.rstrip() for x in Path(tgt_path).open().readlines()]
+ packed_src, packed_tgt = pack_examples(tok, src_docs, tgt_docs, max_tokens)
+ print(f"packed {split} split from {len(src_docs)} examples -> {len(packed_src)}.")
+ Path(save_path / f"{split}.source").open("w").write("\n".join(packed_src))
+ Path(save_path / f"{split}.target").open("w").write("\n".join(packed_tgt))
+ for split in ["val", "test"]:
+ src_path, tgt_path = data_dir / f"{split}.source", data_dir / f"{split}.target"
+ shutil.copyfile(src_path, save_path / f"{split}.source")
+ shutil.copyfile(tgt_path, save_path / f"{split}.target")
+
+
+def packer_cli():
+ parser = argparse.ArgumentParser()
+ parser.add_argument("--tok_name", type=str, help="like facebook/bart-large-cnn,google-t5/t5-base, etc.")
+ parser.add_argument("--max_seq_len", type=int, default=128)
+ parser.add_argument("--data_dir", type=str)
+ parser.add_argument("--save_path", type=str)
+ args = parser.parse_args()
+ tokenizer = AutoTokenizer.from_pretrained(args.tok_name)
+ return pack_data_dir(tokenizer, Path(args.data_dir), args.max_seq_len, args.save_path)
+
+
+if __name__ == "__main__":
+ packer_cli()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..434f647adea299b8dea378171fa687d38d78ead6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/requirements.txt
@@ -0,0 +1,20 @@
+tensorboard
+scikit-learn
+seqeval
+psutil
+sacrebleu
+rouge-score
+tensorflow_datasets
+matplotlib
+git-python==1.0.3
+faiss-cpu
+streamlit
+elasticsearch
+nltk
+pandas
+datasets >= 1.1.3
+fire
+pytest<8.0.1
+conllu
+sentencepiece != 0.1.92
+protobuf
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/romanian_postprocessing.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/romanian_postprocessing.md
new file mode 100644
index 0000000000000000000000000000000000000000..938f0d1d7227f5687ec45f35f8dcff659172dfe2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/romanian_postprocessing.md
@@ -0,0 +1,65 @@
+### Motivation
+Without processing, english-> romanian mbart-large-en-ro gets BLEU score 26.8 on the WMT data.
+With post processing, it can score 37..
+Here is the postprocessing code, stolen from @mjpost in this [issue](https://github.com/pytorch/fairseq/issues/1758)
+
+
+
+### Instructions
+Note: You need to have your test_generations.txt before you start this process.
+(1) Setup `mosesdecoder` and `wmt16-scripts`
+```bash
+cd $HOME
+git clone git@github.com:moses-smt/mosesdecoder.git
+cd mosesdecoder
+git clone git@github.com:rsennrich/wmt16-scripts.git
+```
+
+(2) define a function for post processing.
+ It removes diacritics and does other things I don't understand
+```bash
+ro_post_process () {
+ sys=$1
+ ref=$2
+ export MOSES_PATH=$HOME/mosesdecoder
+ REPLACE_UNICODE_PUNCT=$MOSES_PATH/scripts/tokenizer/replace-unicode-punctuation.perl
+ NORM_PUNC=$MOSES_PATH/scripts/tokenizer/normalize-punctuation.perl
+ REM_NON_PRINT_CHAR=$MOSES_PATH/scripts/tokenizer/remove-non-printing-char.perl
+ REMOVE_DIACRITICS=$MOSES_PATH/wmt16-scripts/preprocess/remove-diacritics.py
+ NORMALIZE_ROMANIAN=$MOSES_PATH/wmt16-scripts/preprocess/normalise-romanian.py
+ TOKENIZER=$MOSES_PATH/scripts/tokenizer/tokenizer.perl
+
+
+
+ lang=ro
+ for file in $sys $ref; do
+ cat $file \
+ | $REPLACE_UNICODE_PUNCT \
+ | $NORM_PUNC -l $lang \
+ | $REM_NON_PRINT_CHAR \
+ | $NORMALIZE_ROMANIAN \
+ | $REMOVE_DIACRITICS \
+ | $TOKENIZER -no-escape -l $lang \
+ > $(basename $file).tok
+ done
+ # compute BLEU
+ cat $(basename $sys).tok | sacrebleu -tok none -s none -b $(basename $ref).tok
+}
+```
+
+(3) Call the function on test_generations.txt and test.target
+For example,
+```bash
+ro_post_process enro_finetune/test_generations.txt wmt_en_ro/test.target
+```
+This will split out a new blue score and write a new fine called `test_generations.tok` with post-processed outputs.
+
+
+
+
+
+
+
+
+
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/rouge_cli.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/rouge_cli.py
new file mode 100644
index 0000000000000000000000000000000000000000..cd636bbcd1c10ca34ae36f8d348ef97a09c0e293
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/rouge_cli.py
@@ -0,0 +1,31 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import fire
+
+from utils import calculate_rouge, save_json
+
+
+def calculate_rouge_path(pred_path, tgt_path, save_path=None, **kwargs):
+ """Kwargs will be passed to calculate_rouge"""
+ pred_lns = [x.strip() for x in open(pred_path).readlines()]
+ tgt_lns = [x.strip() for x in open(tgt_path).readlines()][: len(pred_lns)]
+ metrics = calculate_rouge(pred_lns, tgt_lns, **kwargs)
+ if save_path is not None:
+ save_json(metrics, save_path, indent=None)
+ return metrics # these print nicely
+
+
+if __name__ == "__main__":
+ fire.Fire(calculate_rouge_path)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/run_distributed_eval.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/run_distributed_eval.py
new file mode 100644
index 0000000000000000000000000000000000000000..40a946f81c5e15eab347c1ded3b71282735978e0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/run_distributed_eval.py
@@ -0,0 +1,262 @@
+#!/usr/bin/env python
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import argparse
+import shutil
+import time
+from json import JSONDecodeError
+from logging import getLogger
+from pathlib import Path
+from typing import Dict, List
+
+import torch
+from torch.utils.data import DataLoader
+from tqdm import tqdm
+
+from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+from utils import (
+ Seq2SeqDataset,
+ calculate_bleu,
+ calculate_rouge,
+ chunks,
+ lmap,
+ load_json,
+ parse_numeric_n_bool_cl_kwargs,
+ save_json,
+ use_task_specific_params,
+ write_txt_file,
+)
+
+
+logger = getLogger(__name__)
+
+
+def eval_data_dir(
+ data_dir,
+ save_dir: str,
+ model_name: str,
+ bs: int = 8,
+ max_source_length: int = 1024,
+ type_path="val",
+ n_obs=None,
+ fp16=False,
+ task="summarization",
+ local_rank=None,
+ num_return_sequences=1,
+ dataset_kwargs: Dict = None,
+ prefix="",
+ **generate_kwargs,
+) -> Dict:
+ """Run evaluation on part of the data for one gpu and save to {save_dir}/rank_{rank}_output.json"""
+ model_name = str(model_name)
+ assert local_rank is not None
+ torch.distributed.init_process_group(backend="nccl", rank=local_rank)
+
+ save_dir = Path(save_dir)
+ save_path = save_dir.joinpath(f"rank_{local_rank}_output.json")
+ torch.cuda.set_device(local_rank)
+ model = AutoModelForSeq2SeqLM.from_pretrained(model_name).cuda()
+ if fp16:
+ model = model.half()
+ # determine if we need to increase num_beams
+ use_task_specific_params(model, task) # update config with task specific params
+ num_beams = generate_kwargs.pop("num_beams", model.config.num_beams) # AttributeError risk?
+ if num_return_sequences > num_beams:
+ num_beams = num_return_sequences
+
+ tokenizer = AutoTokenizer.from_pretrained(model_name)
+ logger.info(f"Inferred tokenizer type: {tokenizer.__class__}") # if this is wrong, check config.model_type.
+
+ if max_source_length is None:
+ max_source_length = tokenizer.model_max_length
+ if prefix is None:
+ prefix = prefix or getattr(model.config, "prefix", "") or ""
+ ds = Seq2SeqDataset(
+ tokenizer,
+ data_dir,
+ max_source_length,
+ max_target_length=1024,
+ type_path=type_path,
+ n_obs=n_obs,
+ prefix=prefix,
+ **dataset_kwargs,
+ )
+ # I set shuffle=True for a more accurate progress bar.
+ # If all the longest samples are first, the prog bar estimate is too high at the beginning.
+ sampler = ds.make_sortish_sampler(bs, distributed=True, add_extra_examples=False, shuffle=True)
+ data_loader = DataLoader(ds, sampler=sampler, batch_size=bs, collate_fn=ds.collate_fn)
+ results = []
+ for batch in tqdm(data_loader):
+ summaries = model.generate(
+ input_ids=batch["input_ids"].to(model.device),
+ attention_mask=batch["attention_mask"].to(model.device),
+ num_return_sequences=num_return_sequences,
+ num_beams=num_beams,
+ **generate_kwargs,
+ )
+ preds = tokenizer.batch_decode(summaries, skip_special_tokens=True, clean_up_tokenization_spaces=False)
+ ids = batch["ids"]
+ if num_return_sequences > 1:
+ preds = chunks(preds, num_return_sequences) # batch size chunks, each of size num_return_seq
+ for i, pred in enumerate(preds):
+ results.append({"pred": pred, "id": ids[i].item()})
+ save_json(results, save_path)
+ return results, sampler.num_replicas
+
+
+def run_generate():
+ parser = argparse.ArgumentParser(
+ epilog="Unspecified args like --num_beams=2 --decoder_start_token_id=4 are passed to model.generate"
+ )
+ parser.add_argument("--data_dir", type=str, help="like cnn_dm/test.source")
+ parser.add_argument(
+ "--model_name",
+ type=str,
+ help="like facebook/bart-large-cnn,google-t5/t5-base, etc.",
+ default="sshleifer/distilbart-xsum-12-3",
+ )
+ parser.add_argument("--save_dir", type=str, help="where to save", default="tmp_gen")
+ parser.add_argument("--max_source_length", type=int, default=None)
+ parser.add_argument(
+ "--type_path", type=str, default="test", help="which subset to evaluate typically train/val/test"
+ )
+ parser.add_argument("--task", type=str, default="summarization", help="used for task_specific_params + metrics")
+ parser.add_argument("--bs", type=int, default=8, required=False, help="batch size")
+ parser.add_argument(
+ "--local_rank", type=int, default=-1, required=False, help="should be passed by distributed.launch"
+ )
+
+ parser.add_argument(
+ "--n_obs", type=int, default=None, required=False, help="How many observations. Defaults to all."
+ )
+ parser.add_argument(
+ "--num_return_sequences", type=int, default=1, required=False, help="How many sequences to return"
+ )
+ parser.add_argument(
+ "--sync_timeout",
+ type=int,
+ default=600,
+ required=False,
+ help="How long should master process wait for other processes to finish.",
+ )
+ parser.add_argument("--src_lang", type=str, default=None, required=False)
+ parser.add_argument("--tgt_lang", type=str, default=None, required=False)
+ parser.add_argument(
+ "--prefix", type=str, required=False, default=None, help="will be added to the beginning of src examples"
+ )
+ parser.add_argument("--fp16", action="store_true")
+ parser.add_argument("--debug", action="store_true")
+ start_time = time.time()
+ args, rest = parser.parse_known_args()
+ generate_kwargs = parse_numeric_n_bool_cl_kwargs(rest)
+ if generate_kwargs and args.local_rank <= 0:
+ print(f"parsed the following generate kwargs: {generate_kwargs}")
+ json_save_dir = Path(args.save_dir + "_tmp")
+ Path(json_save_dir).mkdir(exist_ok=True) # this handles locking.
+ intermediate_files = list(json_save_dir.glob("rank_*.json"))
+ if intermediate_files:
+ raise ValueError(f"Found files at {json_save_dir} please move or remove them.")
+ # In theory, a node could finish and save before another node hits this. If this happens, we can address later.
+ dataset_kwargs = {}
+ if args.src_lang is not None:
+ dataset_kwargs["src_lang"] = args.src_lang
+ if args.tgt_lang is not None:
+ dataset_kwargs["tgt_lang"] = args.tgt_lang
+
+ Path(args.save_dir).mkdir(exist_ok=True)
+ results, num_replicas = eval_data_dir(
+ args.data_dir,
+ json_save_dir,
+ args.model_name,
+ type_path=args.type_path,
+ bs=args.bs,
+ fp16=args.fp16,
+ task=args.task,
+ local_rank=args.local_rank,
+ n_obs=args.n_obs,
+ max_source_length=args.max_source_length,
+ num_return_sequences=args.num_return_sequences,
+ prefix=args.prefix,
+ dataset_kwargs=dataset_kwargs,
+ **generate_kwargs,
+ )
+
+ if args.local_rank <= 0:
+ save_dir = Path(args.save_dir)
+ save_dir.mkdir(exist_ok=True)
+ partial_results = gather_results_from_each_node(num_replicas, json_save_dir, args.sync_timeout)
+ preds = combine_partial_results(partial_results)
+ if args.num_return_sequences > 1:
+ save_path = save_dir.joinpath("pseudolabel_results.json")
+ print(f"Saving aggregated results at {save_path}, intermediate in {json_save_dir}/")
+ save_json(preds, save_path)
+ return
+ tgt_file = Path(args.data_dir).joinpath(args.type_path + ".target")
+ with open(tgt_file) as f:
+ labels = [x.rstrip() for x in f.readlines()][: len(preds)]
+
+ # Calculate metrics, save metrics, and save _generations.txt
+ calc_bleu = "translation" in args.task
+ score_fn = calculate_bleu if calc_bleu else calculate_rouge
+ metric_name = "bleu" if calc_bleu else "rouge"
+ metrics: Dict = score_fn(preds, labels)
+ metrics["n_obs"] = len(preds)
+ runtime = time.time() - start_time
+ metrics["seconds_per_sample"] = round(runtime / metrics["n_obs"], 4)
+ metrics["n_gpus"] = num_replicas
+ # TODO(@stas00): add whatever metadata to metrics
+ metrics_save_path = save_dir.joinpath(f"{args.type_path}_{metric_name}.json")
+ save_json(metrics, metrics_save_path, indent=None)
+ print(metrics)
+ write_txt_file(preds, save_dir.joinpath(f"{args.type_path}_generations.txt"))
+ if args.debug:
+ write_txt_file(labels, save_dir.joinpath(f"{args.type_path}.target"))
+ else:
+ shutil.rmtree(json_save_dir)
+
+
+def combine_partial_results(partial_results) -> List:
+ """Concatenate partial results into one file, then sort it by id."""
+ records = []
+ for partial_result in partial_results:
+ records.extend(partial_result)
+ records = sorted(records, key=lambda x: x["id"])
+ preds = [x["pred"] for x in records]
+ return preds
+
+
+def gather_results_from_each_node(num_replicas, save_dir, timeout) -> List[Dict[str, List]]:
+ # WAIT FOR lots of .json files
+ start_wait = time.time()
+ logger.info("waiting for all nodes to finish")
+ json_data = None
+ while (time.time() - start_wait) < timeout:
+ json_files = list(save_dir.glob("rank_*.json"))
+ if len(json_files) < num_replicas:
+ continue
+ try:
+ # make sure all json files are fully saved
+ json_data = lmap(load_json, json_files)
+ return json_data
+ except JSONDecodeError:
+ continue
+ else:
+ raise TimeoutError("Rank 0 gave up on waiting for other processes")
+ # Unreachable
+
+
+if __name__ == "__main__":
+ # Usage for MT:
+ run_generate()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/run_eval.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/run_eval.py
new file mode 100644
index 0000000000000000000000000000000000000000..f69e5d51264c7863d7af8902784e4a2154ca87bf
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/run_eval.py
@@ -0,0 +1,185 @@
+#!/usr/bin/env python
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import argparse
+import datetime
+import json
+import time
+import warnings
+from logging import getLogger
+from pathlib import Path
+from typing import Dict, List
+
+import torch
+from tqdm import tqdm
+
+from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+from utils import calculate_bleu, calculate_rouge, chunks, parse_numeric_n_bool_cl_kwargs, use_task_specific_params
+
+
+logger = getLogger(__name__)
+
+
+DEFAULT_DEVICE = "cuda" if torch.cuda.is_available() else "cpu"
+
+
+def generate_summaries_or_translations(
+ examples: List[str],
+ out_file: str,
+ model_name: str,
+ batch_size: int = 8,
+ device: str = DEFAULT_DEVICE,
+ fp16=False,
+ task="summarization",
+ prefix=None,
+ **generate_kwargs,
+) -> Dict:
+ """Save model.generate results to , and return how long it took."""
+ fout = Path(out_file).open("w", encoding="utf-8")
+ model_name = str(model_name)
+ model = AutoModelForSeq2SeqLM.from_pretrained(model_name).to(device)
+ if fp16:
+ model = model.half()
+
+ tokenizer = AutoTokenizer.from_pretrained(model_name)
+ logger.info(f"Inferred tokenizer type: {tokenizer.__class__}") # if this is wrong, check config.model_type.
+
+ start_time = time.time()
+ # update config with task specific params
+ use_task_specific_params(model, task)
+ if prefix is None:
+ prefix = prefix or getattr(model.config, "prefix", "") or ""
+ for examples_chunk in tqdm(list(chunks(examples, batch_size))):
+ examples_chunk = [prefix + text for text in examples_chunk]
+ batch = tokenizer(examples_chunk, return_tensors="pt", truncation=True, padding="longest").to(device)
+ summaries = model.generate(
+ input_ids=batch.input_ids,
+ attention_mask=batch.attention_mask,
+ **generate_kwargs,
+ )
+ dec = tokenizer.batch_decode(summaries, skip_special_tokens=True, clean_up_tokenization_spaces=False)
+ for hypothesis in dec:
+ fout.write(hypothesis + "\n")
+ fout.flush()
+ fout.close()
+ runtime = int(time.time() - start_time) # seconds
+ n_obs = len(examples)
+ return {"n_obs": n_obs, "runtime": runtime, "seconds_per_sample": round(runtime / n_obs, 4)}
+
+
+def datetime_now():
+ return datetime.datetime.now().strftime("%Y-%m-%d %H:%M:%S")
+
+
+def run_generate(verbose=True):
+ """
+
+ Takes input text, generates output, and then using reference calculates the BLEU scores.
+
+ The results are saved to a file and returned to the caller, and printed out unless ``verbose=False`` is passed.
+
+ Args:
+ verbose (:obj:`bool`, `optional`, defaults to :obj:`True`): print results to stdout
+
+ Returns:
+ a tuple: ``(scores, params}``
+ - ``scores``: a dict of scores data ``{'bleu': 39.6501, 'n_obs': 2000, 'runtime': 186, 'seconds_per_sample': 0.093}``
+ - ``params``: a dict of custom params, e.g. ``{'num_beams': 5, 'length_penalty': 0.8}``
+ """
+
+ parser = argparse.ArgumentParser()
+ parser.add_argument("model_name", type=str, help="like facebook/bart-large-cnn,google-t5/t5-base, etc.")
+ parser.add_argument("input_path", type=str, help="like cnn_dm/test.source")
+ parser.add_argument("save_path", type=str, help="where to save summaries")
+ parser.add_argument("--reference_path", type=str, required=False, help="like cnn_dm/test.target")
+ parser.add_argument("--score_path", type=str, required=False, default="metrics.json", help="where to save metrics")
+ parser.add_argument("--device", type=str, required=False, default=DEFAULT_DEVICE, help="cuda, cuda:1, cpu etc.")
+ parser.add_argument(
+ "--prefix", type=str, required=False, default=None, help="will be added to the beginning of src examples"
+ )
+ parser.add_argument("--task", type=str, default="summarization", help="used for task_specific_params + metrics")
+ parser.add_argument("--bs", type=int, default=8, required=False, help="batch size")
+ parser.add_argument(
+ "--n_obs", type=int, default=-1, required=False, help="How many observations. Defaults to all."
+ )
+ parser.add_argument("--fp16", action="store_true")
+ parser.add_argument("--dump-args", action="store_true", help="print the custom hparams with the results")
+ parser.add_argument(
+ "--info",
+ nargs="?",
+ type=str,
+ const=datetime_now(),
+ help=(
+ "use in conjunction w/ --dump-args to print with the results whatever other info you'd like, e.g."
+ " lang=en-ru. If no value is passed, the current datetime string will be used."
+ ),
+ )
+ # Unspecified args like --num_beams=2 --decoder_start_token_id=4 are passed to model.generate
+ args, rest = parser.parse_known_args()
+ parsed_args = parse_numeric_n_bool_cl_kwargs(rest)
+ if parsed_args and verbose:
+ print(f"parsed the following generate kwargs: {parsed_args}")
+ examples = [" " + x.rstrip() if "t5" in args.model_name else x.rstrip() for x in open(args.input_path).readlines()]
+ if args.n_obs > 0:
+ examples = examples[: args.n_obs]
+ Path(args.save_path).parent.mkdir(exist_ok=True)
+
+ if args.reference_path is None and Path(args.score_path).exists():
+ warnings.warn(f"score_path {args.score_path} will be overwritten unless you type ctrl-c.")
+
+ if args.device == "cpu" and args.fp16:
+ # this mix leads to RuntimeError: "threshold_cpu" not implemented for 'Half'
+ raise ValueError("Can't mix --fp16 and --device cpu")
+
+ runtime_metrics = generate_summaries_or_translations(
+ examples,
+ args.save_path,
+ args.model_name,
+ batch_size=args.bs,
+ device=args.device,
+ fp16=args.fp16,
+ task=args.task,
+ prefix=args.prefix,
+ **parsed_args,
+ )
+
+ if args.reference_path is None:
+ return {}
+
+ # Compute scores
+ score_fn = calculate_bleu if "translation" in args.task else calculate_rouge
+ output_lns = [x.rstrip() for x in open(args.save_path).readlines()]
+ reference_lns = [x.rstrip() for x in open(args.reference_path).readlines()][: len(output_lns)]
+ scores: dict = score_fn(output_lns, reference_lns)
+ scores.update(runtime_metrics)
+
+ if args.dump_args:
+ scores.update(parsed_args)
+ if args.info:
+ scores["info"] = args.info
+
+ if verbose:
+ print(scores)
+
+ if args.score_path is not None:
+ json.dump(scores, open(args.score_path, "w"))
+
+ return scores
+
+
+if __name__ == "__main__":
+ # Usage for MT:
+ # python run_eval.py MODEL_NAME $DATA_DIR/test.source $save_dir/test_translations.txt --reference_path $DATA_DIR/test.target --score_path $save_dir/test_bleu.json --task translation $@
+ run_generate(verbose=True)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/run_eval_search.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/run_eval_search.py
new file mode 100644
index 0000000000000000000000000000000000000000..9b5debfb2795eeace43c95153a04df33f5011c2b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/run_eval_search.py
@@ -0,0 +1,158 @@
+#!/usr/bin/env python
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import argparse
+import itertools
+import operator
+import sys
+from collections import OrderedDict
+
+from run_eval import datetime_now, run_generate
+
+from utils import ROUGE_KEYS
+
+
+# A table of supported tasks and the list of scores in the order of importance to be sorted by.
+# To add a new task, simply list the score names that `run_eval.run_generate()` returns
+task_score_names = {
+ "translation": ["bleu"],
+ "summarization": ROUGE_KEYS,
+}
+
+
+def parse_search_arg(search):
+ groups = search.split()
+ entries = dict((g.split("=") for g in groups))
+ entry_names = list(entries.keys())
+ sets = [[f"--{k} {v}" for v in vs.split(":")] for k, vs in entries.items()]
+ matrix = [list(x) for x in itertools.product(*sets)]
+ return matrix, entry_names
+
+
+def run_search():
+ """
+ Run parametric search over the desired hparam space with help of ``run_eval.py``.
+
+ All the arguments except ``--search`` are passed to ``run_eval.py`` as is. The values inside of "--search" are parsed, reformatted and fed to ``run_eval.py`` as additional args.
+
+ The format for the ``--search`` value is a simple string with hparams and colon separated values to try, e.g.:
+ ```
+ --search "num_beams=5:10 length_penalty=0.8:1.0:1.2 early_stopping=true:false"
+ ```
+ which will generate ``12`` ``(2*3*2)`` searches for a product of each hparam. For example the example that was just used will invoke ``run_eval.py`` repeatedly with:
+
+ ```
+ --num_beams 5 --length_penalty 0.8 --early_stopping true
+ --num_beams 5 --length_penalty 0.8 --early_stopping false
+ [...]
+ --num_beams 10 --length_penalty 1.2 --early_stopping false
+ ```
+
+ On completion, this function prints a markdown table of the results sorted by the best BLEU score and the winning arguments.
+
+
+ """
+ prog = sys.argv[0]
+
+ parser = argparse.ArgumentParser(
+ usage=(
+ "\n\nImportant: this script accepts all arguments `run_eval.py` accepts and then a few extra, therefore"
+ " refer to `run_eval.py -h` for the complete list."
+ )
+ )
+ parser.add_argument(
+ "--search",
+ type=str,
+ required=False,
+ help='param space to search, e.g. "num_beams=5:10 length_penalty=0.8:1.0:1.2"',
+ )
+ parser.add_argument(
+ "--bs", type=int, default=8, required=False, help="initial batch size (may get reduced if it's too big)"
+ )
+ parser.add_argument("--task", type=str, help="used for task_specific_params + metrics")
+ parser.add_argument(
+ "--info",
+ nargs="?",
+ type=str,
+ const=datetime_now(),
+ help=(
+ "add custom notes to be printed before the results table. If no value is passed, the current datetime"
+ " string will be used."
+ ),
+ )
+ args, args_main = parser.parse_known_args()
+ # we share some of the args
+ args_main.extend(["--task", args.task])
+ args_normal = [prog] + args_main
+
+ # to support variations like translation_en_to_de"
+ task = "translation" if "translation" in args.task else "summarization"
+
+ matrix, col_names = parse_search_arg(args.search)
+ col_names[0:0] = task_score_names[task] # score cols first
+ col_widths = {col: len(str(col)) for col in col_names}
+ results = []
+ for r in matrix:
+ hparams = dict((x.replace("--", "").split() for x in r))
+ args_exp = " ".join(r).split()
+ args_exp.extend(["--bs", str(args.bs)]) # in case we need to reduce its size due to CUDA OOM
+ sys.argv = args_normal + args_exp
+
+ # XXX: need to trap CUDA OOM and lower args.bs if that happens and retry
+
+ scores = run_generate(verbose=False)
+ # make sure scores are first in the table
+ result = OrderedDict()
+ for score in task_score_names[task]:
+ result[score] = scores[score]
+ result.update(hparams)
+ results.append(result)
+
+ # find widest entries
+ for k, v in result.items():
+ l = len(str(v))
+ if l > col_widths[k]:
+ col_widths[k] = l
+
+ results_sorted = sorted(results, key=operator.itemgetter(*task_score_names[task]), reverse=True)
+ print(" | ".join([f"{col:{col_widths[col]}}" for col in col_names]))
+ print(" | ".join([f"{'-'*col_widths[col]}" for col in col_names]))
+ for row in results_sorted:
+ print(" | ".join([f"{row[col]:{col_widths[col]}}" for col in col_names]))
+
+ best = results_sorted[0]
+ for score in task_score_names[task]:
+ del best[score]
+ best_args = [f"--{k} {v}" for k, v in best.items()]
+ dyn_args = ["--bs", str(args.bs)]
+ if args.info:
+ print(f"\nInfo: {args.info}")
+ print("\nBest score args:")
+ print(" ".join(args_main + best_args + dyn_args))
+
+ return results_sorted
+
+
+if __name__ == "__main__":
+ # Usage:
+ # [normal-run_eval_search.py cmd plus] \
+ # --search="num_beams=1:5:10 length_penalty=0.8:1:1.2 early_stopping=true:false"
+ #
+ # Example:
+ # PYTHONPATH="src:examples/seq2seq" python examples/seq2seq/run_eval_search.py $MODEL_NAME \
+ # $DATA_DIR/val.source $SAVE_DIR/test_translations.txt --reference_path $DATA_DIR/val.target \
+ # --score_path $SAVE_DIR/test_bleu.json --bs $BS --task translation \
+ # --search="num_beams=1:5:10 length_penalty=0.8:1:1.2 early_stopping=true:false"
+ run_search()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/save_len_file.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/save_len_file.py
new file mode 100644
index 0000000000000000000000000000000000000000..9e73b59e7e5a2b0a480779db987464f8b8320cee
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/save_len_file.py
@@ -0,0 +1,56 @@
+#!/usr/bin/env python
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import fire
+from torch.utils.data import DataLoader
+from tqdm import tqdm
+
+from transformers import AutoTokenizer
+from utils import Seq2SeqDataset, pickle_save
+
+
+def save_len_file(
+ tokenizer_name, data_dir, max_source_length=1024, max_target_length=1024, consider_target=False, **kwargs
+):
+ """Save max(src_len, tgt_len) for each example to allow dynamic batching."""
+ tok = AutoTokenizer.from_pretrained(tokenizer_name)
+ train_ds = Seq2SeqDataset(tok, data_dir, max_source_length, max_target_length, type_path="train", **kwargs)
+ pad = tok.pad_token_id
+
+ def get_lens(ds):
+ dl = tqdm(
+ DataLoader(ds, batch_size=512, num_workers=8, shuffle=False, collate_fn=ds.collate_fn),
+ desc=str(ds.len_file),
+ )
+ max_lens = []
+ for batch in dl:
+ src_lens = batch["input_ids"].ne(pad).sum(1).tolist()
+ tgt_lens = batch["labels"].ne(pad).sum(1).tolist()
+ if consider_target:
+ for src, tgt in zip(src_lens, tgt_lens):
+ max_lens.append(max(src, tgt))
+ else:
+ max_lens.extend(src_lens)
+ return max_lens
+
+ train_lens = get_lens(train_ds)
+ val_ds = Seq2SeqDataset(tok, data_dir, max_source_length, max_target_length, type_path="val", **kwargs)
+ val_lens = get_lens(val_ds)
+ pickle_save(train_lens, train_ds.len_file)
+ pickle_save(val_lens, val_ds.len_file)
+
+
+if __name__ == "__main__":
+ fire.Fire(save_len_file)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/save_randomly_initialized_model.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/save_randomly_initialized_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..1b7b17fde8d6b0e7f2eed7420c0570012558b1ed
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/save_randomly_initialized_model.py
@@ -0,0 +1,39 @@
+#!/usr/bin/env python
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import fire
+
+from transformers import AutoConfig, AutoModelForSeq2SeqLM, AutoTokenizer
+
+
+def save_randomly_initialized_version(config_name: str, save_dir: str, **config_kwargs):
+ """Save a randomly initialized version of a model using a pretrained config.
+ Args:
+ config_name: which config to use
+ save_dir: where to save the resulting model and tokenizer
+ config_kwargs: Passed to AutoConfig
+
+ Usage::
+ save_randomly_initialized_version("facebook/bart-large-cnn", "distilbart_random_cnn_6_3", encoder_layers=6, decoder_layers=3, num_beams=3)
+ """
+ cfg = AutoConfig.from_pretrained(config_name, **config_kwargs)
+ model = AutoModelForSeq2SeqLM.from_config(cfg)
+ model.save_pretrained(save_dir)
+ AutoTokenizer.from_pretrained(config_name).save_pretrained(save_dir)
+ return model
+
+
+if __name__ == "__main__":
+ fire.Fire(save_randomly_initialized_version)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/sentence_splitter.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/sentence_splitter.py
new file mode 100644
index 0000000000000000000000000000000000000000..54a07967efa31c31ee1219d1a25808df0108388a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/sentence_splitter.py
@@ -0,0 +1,35 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import re
+
+from filelock import FileLock
+
+
+try:
+ import nltk
+
+ NLTK_AVAILABLE = True
+except (ImportError, ModuleNotFoundError):
+ NLTK_AVAILABLE = False
+
+if NLTK_AVAILABLE:
+ with FileLock(".lock") as lock:
+ nltk.download("punkt", quiet=True)
+
+
+def add_newline_to_end_of_each_sentence(x: str) -> str:
+ """This was added to get rougeLsum scores matching published rougeL scores for BART and PEGASUS."""
+ re.sub("", "", x) # remove pegasus newline char
+ assert NLTK_AVAILABLE, "nltk must be installed to separate newlines between sentences. (pip install nltk)"
+ return "\n".join(nltk.sent_tokenize(x))
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/seq2seq_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/seq2seq_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..0c981a201dd4b1730ecae1c60dafc81bb9828297
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/seq2seq_trainer.py
@@ -0,0 +1,250 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from typing import Any, Dict, List, Optional, Tuple, Union
+
+import torch
+from torch import nn
+from torch.utils.data import DistributedSampler, RandomSampler
+
+from transformers import PreTrainedModel, Trainer, logging
+from transformers.models.fsmt.configuration_fsmt import FSMTConfig
+from transformers.optimization import (
+ Adafactor,
+ AdamW,
+ get_constant_schedule,
+ get_constant_schedule_with_warmup,
+ get_cosine_schedule_with_warmup,
+ get_cosine_with_hard_restarts_schedule_with_warmup,
+ get_linear_schedule_with_warmup,
+ get_polynomial_decay_schedule_with_warmup,
+)
+from transformers.trainer_pt_utils import get_tpu_sampler
+from transformers.training_args import ParallelMode
+from transformers.utils import is_torch_xla_available
+
+
+logger = logging.get_logger(__name__)
+
+arg_to_scheduler = {
+ "linear": get_linear_schedule_with_warmup,
+ "cosine": get_cosine_schedule_with_warmup,
+ "cosine_w_restarts": get_cosine_with_hard_restarts_schedule_with_warmup,
+ "polynomial": get_polynomial_decay_schedule_with_warmup,
+ "constant": get_constant_schedule,
+ "constant_w_warmup": get_constant_schedule_with_warmup,
+}
+
+
+class Seq2SeqTrainer(Trainer):
+ def __init__(self, config=None, data_args=None, *args, **kwargs):
+ super().__init__(*args, **kwargs)
+
+ if config is None:
+ assert isinstance(self.model, PreTrainedModel), (
+ "If no `config` is passed the model to be trained has to be of type `PreTrainedModel`, but is"
+ f" {self.model.__class__}"
+ )
+ self.config = self.model.config
+ else:
+ self.config = config
+
+ self.data_args = data_args
+ self.vocab_size = self.config.tgt_vocab_size if isinstance(self.config, FSMTConfig) else self.config.vocab_size
+
+ if self.args.label_smoothing != 0 or (self.data_args is not None and self.data_args.ignore_pad_token_for_loss):
+ assert self.config.pad_token_id is not None, (
+ "Make sure that `config.pad_token_id` is correctly defined when ignoring `pad_token` for loss"
+ " calculation or doing label smoothing."
+ )
+
+ if self.config.pad_token_id is None and self.config.eos_token_id is not None:
+ logger.warning(
+ f"The `config.pad_token_id` is `None`. Using `config.eos_token_id` = {self.config.eos_token_id} for"
+ " padding.."
+ )
+
+ if self.args.label_smoothing == 0:
+ self.loss_fn = torch.nn.CrossEntropyLoss(ignore_index=self.config.pad_token_id)
+ else:
+ # dynamically import label_smoothed_nll_loss
+ from utils import label_smoothed_nll_loss
+
+ self.loss_fn = label_smoothed_nll_loss
+
+ def create_optimizer_and_scheduler(self, num_training_steps: int):
+ """
+ Setup the optimizer and the learning rate scheduler.
+
+ We provide a reasonable default that works well. If you want to use something else, you can pass a tuple in the
+ Trainer's init through :obj:`optimizers`, or subclass and override this method in a subclass.
+ """
+ if self.optimizer is None:
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in self.model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": self.args.weight_decay,
+ },
+ {
+ "params": [p for n, p in self.model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ optimizer_cls = Adafactor if self.args.adafactor else AdamW
+ if self.args.adafactor:
+ optimizer_cls = Adafactor
+ optimizer_kwargs = {"scale_parameter": False, "relative_step": False}
+ else:
+ optimizer_cls = AdamW
+ optimizer_kwargs = {
+ "betas": (self.args.adam_beta1, self.args.adam_beta2),
+ "eps": self.args.adam_epsilon,
+ }
+ optimizer_kwargs["lr"] = self.args.learning_rate
+ self.optimizer = optimizer_cls(optimizer_grouped_parameters, **optimizer_kwargs)
+
+ if self.lr_scheduler is None:
+ self.lr_scheduler = self._get_lr_scheduler(num_training_steps)
+ else: # ignoring --lr_scheduler
+ logger.warning("scheduler is passed to `Seq2SeqTrainer`, `--lr_scheduler` arg is ignored.")
+
+ def _get_lr_scheduler(self, num_training_steps):
+ schedule_func = arg_to_scheduler[self.args.lr_scheduler]
+ if self.args.lr_scheduler == "constant":
+ scheduler = schedule_func(self.optimizer)
+ elif self.args.lr_scheduler == "constant_w_warmup":
+ scheduler = schedule_func(self.optimizer, num_warmup_steps=self.args.warmup_steps)
+ else:
+ scheduler = schedule_func(
+ self.optimizer, num_warmup_steps=self.args.warmup_steps, num_training_steps=num_training_steps
+ )
+ return scheduler
+
+ def _get_train_sampler(self) -> Optional[torch.utils.data.Sampler]:
+ if isinstance(self.train_dataset, torch.utils.data.IterableDataset):
+ return None
+ elif is_torch_xla_available():
+ return get_tpu_sampler(self.train_dataset)
+ else:
+ if self.args.sortish_sampler:
+ self.train_dataset.make_sortish_sampler(
+ self.args.per_device_train_batch_size,
+ distributed=(self.args.parallel_mode == ParallelMode.DISTRIBUTED),
+ )
+
+ return (
+ RandomSampler(self.train_dataset)
+ if self.args.local_rank == -1
+ else DistributedSampler(self.train_dataset)
+ )
+
+ def _compute_loss(self, model, inputs, labels):
+ if self.args.label_smoothing == 0:
+ if self.data_args is not None and self.data_args.ignore_pad_token_for_loss:
+ # force training to ignore pad token
+ logits = model(**inputs, use_cache=False)[0]
+ loss = self.loss_fn(logits.view(-1, logits.shape[-1]), labels.view(-1))
+ else:
+ # compute usual loss via models
+ loss, logits = model(**inputs, labels=labels, use_cache=False)[:2]
+ else:
+ # compute label smoothed loss
+ logits = model(**inputs, use_cache=False)[0]
+ lprobs = torch.nn.functional.log_softmax(logits, dim=-1)
+ loss, _ = self.loss_fn(lprobs, labels, self.args.label_smoothing, ignore_index=self.config.pad_token_id)
+ return loss, logits
+
+ def compute_loss(self, model, inputs):
+ labels = inputs.pop("labels")
+ loss, _ = self._compute_loss(model, inputs, labels)
+ return loss
+
+ def prediction_step(
+ self,
+ model: nn.Module,
+ inputs: Dict[str, Union[torch.Tensor, Any]],
+ prediction_loss_only: bool,
+ ignore_keys: Optional[List[str]] = None,
+ ) -> Tuple[Optional[float], Optional[torch.Tensor], Optional[torch.Tensor]]:
+ """
+ Perform an evaluation step on :obj:`model` using obj:`inputs`.
+
+ Subclass and override to inject custom behavior.
+
+ Args:
+ model (:obj:`nn.Module`):
+ The model to evaluate.
+ inputs (:obj:`Dict[str, Union[torch.Tensor, Any]]`):
+ The inputs and targets of the model.
+
+ The dictionary will be unpacked before being fed to the model. Most models expect the targets under the
+ argument :obj:`labels`. Check your model's documentation for all accepted arguments.
+ prediction_loss_only (:obj:`bool`):
+ Whether or not to return the loss only.
+
+ Return:
+ Tuple[Optional[float], Optional[torch.Tensor], Optional[torch.Tensor]]:
+ A tuple with the loss, logits and labels (each being optional).
+ """
+ inputs = self._prepare_inputs(inputs)
+
+ gen_kwargs = {
+ "max_length": self.data_args.val_max_target_length
+ if self.data_args is not None
+ else self.config.max_length,
+ "num_beams": self.data_args.eval_beams if self.data_args is not None else self.config.num_beams,
+ }
+
+ if self.args.predict_with_generate and not self.args.prediction_loss_only:
+ generated_tokens = self.model.generate(
+ inputs["input_ids"],
+ attention_mask=inputs["attention_mask"],
+ **gen_kwargs,
+ )
+ # in case the batch is shorter than max length, the output should be padded
+ if generated_tokens.shape[-1] < gen_kwargs["max_length"]:
+ generated_tokens = self._pad_tensors_to_max_len(generated_tokens, gen_kwargs["max_length"])
+
+ labels = inputs.pop("labels")
+ with torch.no_grad():
+ # compute loss on predict data
+ loss, logits = self._compute_loss(model, inputs, labels)
+
+ loss = loss.mean().detach()
+ if self.args.prediction_loss_only:
+ return (loss, None, None)
+
+ logits = generated_tokens if self.args.predict_with_generate else logits
+
+ if labels.shape[-1] < gen_kwargs["max_length"]:
+ labels = self._pad_tensors_to_max_len(labels, gen_kwargs["max_length"])
+
+ return (loss, logits, labels)
+
+ def _pad_tensors_to_max_len(self, tensor, max_length):
+ # If PAD token is not defined at least EOS token has to be defined
+ pad_token_id = self.config.pad_token_id if self.config.pad_token_id is not None else self.config.eos_token_id
+
+ if pad_token_id is None:
+ raise ValueError(
+ "Make sure that either `config.pad_token_id` or `config.eos_token_id` is defined if tensor has to be"
+ f" padded to `max_length`={max_length}"
+ )
+
+ padded_tensor = pad_token_id * torch.ones(
+ (tensor.shape[0], max_length), dtype=tensor.dtype, device=tensor.device
+ )
+ padded_tensor[:, : tensor.shape[-1]] = tensor
+ return padded_tensor
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/seq2seq_training_args.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/seq2seq_training_args.py
new file mode 100644
index 0000000000000000000000000000000000000000..9da1c69262a8c0c3907597ecffd435dc78929919
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/seq2seq_training_args.py
@@ -0,0 +1,60 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import logging
+from dataclasses import dataclass, field
+from typing import Optional
+
+from seq2seq_trainer import arg_to_scheduler
+
+from transformers import TrainingArguments
+
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class Seq2SeqTrainingArguments(TrainingArguments):
+ """
+ Parameters:
+ label_smoothing (:obj:`float`, `optional`, defaults to 0):
+ The label smoothing epsilon to apply (if not zero).
+ sortish_sampler (:obj:`bool`, `optional`, defaults to :obj:`False`):
+ Whether to SortishSampler or not. It sorts the inputs according to lengths in-order to minimizing the padding size.
+ predict_with_generate (:obj:`bool`, `optional`, defaults to :obj:`False`):
+ Whether to use generate to calculate generative metrics (ROUGE, BLEU).
+ """
+
+ label_smoothing: Optional[float] = field(
+ default=0.0, metadata={"help": "The label smoothing epsilon to apply (if not zero)."}
+ )
+ sortish_sampler: bool = field(default=False, metadata={"help": "Whether to SortishSampler or not."})
+ predict_with_generate: bool = field(
+ default=False, metadata={"help": "Whether to use generate to calculate generative metrics (ROUGE, BLEU)."}
+ )
+ adafactor: bool = field(default=False, metadata={"help": "whether to use adafactor"})
+ encoder_layerdrop: Optional[float] = field(
+ default=None, metadata={"help": "Encoder layer dropout probability. Goes into model.config."}
+ )
+ decoder_layerdrop: Optional[float] = field(
+ default=None, metadata={"help": "Decoder layer dropout probability. Goes into model.config."}
+ )
+ dropout: Optional[float] = field(default=None, metadata={"help": "Dropout probability. Goes into model.config."})
+ attention_dropout: Optional[float] = field(
+ default=None, metadata={"help": "Attention dropout probability. Goes into model.config."}
+ )
+ lr_scheduler: Optional[str] = field(
+ default="linear",
+ metadata={"help": f"Which lr scheduler to use. Selected in {sorted(arg_to_scheduler.keys())}"},
+ )
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/fsmt/build-eval-data.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/fsmt/build-eval-data.py
new file mode 100644
index 0000000000000000000000000000000000000000..46487c07ea8432157448c1e4013ab9d01bd6cd65
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/fsmt/build-eval-data.py
@@ -0,0 +1,33 @@
+#!/usr/bin/env python
+
+import io
+import json
+import subprocess
+
+
+pairs = [
+ ["en", "ru"],
+ ["ru", "en"],
+ ["en", "de"],
+ ["de", "en"],
+]
+
+n_objs = 8
+
+
+def get_all_data(pairs, n_objs):
+ text = {}
+ for src, tgt in pairs:
+ pair = f"{src}-{tgt}"
+ cmd = f"sacrebleu -t wmt19 -l {pair} --echo src".split()
+ src_lines = subprocess.run(cmd, stdout=subprocess.PIPE).stdout.decode("utf-8").splitlines()
+ cmd = f"sacrebleu -t wmt19 -l {pair} --echo ref".split()
+ tgt_lines = subprocess.run(cmd, stdout=subprocess.PIPE).stdout.decode("utf-8").splitlines()
+ text[pair] = {"src": src_lines[:n_objs], "tgt": tgt_lines[:n_objs]}
+ return text
+
+
+text = get_all_data(pairs, n_objs)
+filename = "./fsmt_val_data.json"
+with io.open(filename, "w", encoding="utf-8") as f:
+ bleu_data = json.dump(text, f, indent=2, ensure_ascii=False)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/fsmt/fsmt_val_data.json b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/fsmt/fsmt_val_data.json
new file mode 100644
index 0000000000000000000000000000000000000000..f38b305733314aaa134ecdb016b7f3bbea81a6d0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/fsmt/fsmt_val_data.json
@@ -0,0 +1,90 @@
+{
+ "en-ru": {
+ "src": [
+ "Welsh AMs worried about 'looking like muppets'",
+ "There is consternation among some AMs at a suggestion their title should change to MWPs (Member of the Welsh Parliament).",
+ "It has arisen because of plans to change the name of the assembly to the Welsh Parliament.",
+ "AMs across the political spectrum are worried it could invite ridicule.",
+ "One Labour AM said his group was concerned \"it rhymes with Twp and Pwp.\"",
+ "For readers outside of Wales: In Welsh twp means daft and pwp means poo.",
+ "A Plaid AM said the group as a whole was \"not happy\" and has suggested alternatives.",
+ "A Welsh Conservative said his group was \"open minded\" about the name change, but noted it was a short verbal hop from MWP to Muppet."
+ ],
+ "tgt": [
+ "Члены Национальной ассамблеи Уэльса обеспокоены, что \"выглядят как куклы\"",
+ "Некоторые члены Национальной ассамблеи Уэльса в ужасе от предложения о том, что их наименование должно измениться на MPW (члены Парламента Уэльса).",
+ "Этот вопрос был поднят в связи с планами по переименованию ассамблеи в Парламент Уэльса.",
+ "Члены Национальной ассамблеи Уэльса всего политического спектра обеспокоены, что это может породить насмешки.",
+ "Один из лейбористских членов Национальной ассамблеи Уэльса сказал, что его партия обеспокоена тем, что \"это рифмуется с Twp и Pwp\".",
+ "Для читателей за предлами Уэльса: по-валлийски twp означает \"глупый\", а pwp означает \"какашка\".",
+ "Член Национальной ассамблеи от Плайд сказал, что эта партия в целом \"не счастлива\" и предложил альтернативы.",
+ "Представитель Консервативной партии Уэльса сказал, что его партия \"открыта\" к переименованию, но отметил, что между WMP и Muppet небольшая разница в произношении."
+ ]
+ },
+ "ru-en": {
+ "src": [
+ "Названо число готовящихся к отправке в Донбасс новобранцев из Украины",
+ "Официальный представитель Народной милиции самопровозглашенной Луганской Народной Республики (ЛНР) Андрей Марочко заявил, что зимой 2018-2019 года Украина направит в Донбасс не менее 3 тыс. новобранцев.",
+ "По его словам, таким образом Киев планирует \"хоть как-то доукомплектовать подразделения\".",
+ "\"Нежелание граждан Украины проходить службу в рядах ВС Украины, массовые увольнения привели к низкой укомплектованности подразделений\", - рассказал Марочко, которого цитирует \"РИА Новости\".",
+ "Он также не исключил, что реальные цифры призванных в армию украинцев могут быть увеличены в случае необходимости.",
+ "В 2014-2017 годах Киев начал так называемую антитеррористическую операцию (АТО), которую позже сменили на операцию объединенных сил (ООС).",
+ "Предполагалось, что эта мера приведет к усилению роли украинских силовиков в урегулировании ситуации.",
+ "В конце августа 2018 года ситуация в Донбассе обострилась из-за убийства главы ДНР Александра Захарченко."
+ ],
+ "tgt": [
+ "The number of new Ukrainian recruits ready to go to Donbass has become public",
+ "Official representative of the peoples’ militia of the self-proclaimed Lugansk People’s Republic Andrey Marochko claimed that Ukrainian will send at least 3 thousand new recruits to Donbass in winter 2018-2019.",
+ "This is how Kyiv tries “at least somehow to staff the units,” he said.",
+ "“The unwillingness of Ukrainian citizens to serve in the Ukraine’s military forces, mass resignments lead to low understaffing,” said Marochko cited by RIA Novosti.",
+ "Also, he doesn’t exclude that the real numbers of conscripts in the Ukrainian army can be raised is necessary.",
+ "In 2014-2017, Kyiv started so-called antiterrorist operation, that ws later changed to the united forces operation.",
+ "This measure was supposed to strengthen the role of the Ukrainian military in settling the situation.",
+ "In the late August 2018, the situation in Donbass escalated as the DNR head Aleksandr Zakharchenko was killed."
+ ]
+ },
+ "en-de": {
+ "src": [
+ "Welsh AMs worried about 'looking like muppets'",
+ "There is consternation among some AMs at a suggestion their title should change to MWPs (Member of the Welsh Parliament).",
+ "It has arisen because of plans to change the name of the assembly to the Welsh Parliament.",
+ "AMs across the political spectrum are worried it could invite ridicule.",
+ "One Labour AM said his group was concerned \"it rhymes with Twp and Pwp.\"",
+ "For readers outside of Wales: In Welsh twp means daft and pwp means poo.",
+ "A Plaid AM said the group as a whole was \"not happy\" and has suggested alternatives.",
+ "A Welsh Conservative said his group was \"open minded\" about the name change, but noted it was a short verbal hop from MWP to Muppet."
+ ],
+ "tgt": [
+ "Walisische Ageordnete sorgen sich \"wie Dödel auszusehen\"",
+ "Es herrscht Bestürzung unter einigen Mitgliedern der Versammlung über einen Vorschlag, der ihren Titel zu MWPs (Mitglied der walisischen Parlament) ändern soll.",
+ "Der Grund dafür waren Pläne, den Namen der Nationalversammlung in Walisisches Parlament zu ändern.",
+ "Mitglieder aller Parteien der Nationalversammlung haben Bedenken, dass sie sich dadurch Spott aussetzen könnten.",
+ "Ein Labour-Abgeordneter sagte, dass seine Gruppe \"sich mit Twp und Pwp reimt\".",
+ "Hinweis für den Leser: „twp“ im Walisischen bedeutet „bescheuert“ und „pwp“ bedeutet „Kacke“.",
+ "Ein Versammlungsmitglied von Plaid Cymru sagte, die Gruppe als Ganzes sei \"nicht glücklich\" und hat Alternativen vorgeschlagen.",
+ "Ein walisischer Konservativer sagte, seine Gruppe wäre „offen“ für eine Namensänderung, wies aber darauf hin, dass es von „MWP“ (Mitglied des Walisischen Parlaments) nur ein kurzer verbaler Sprung zu „Muppet“ ist."
+ ]
+ },
+ "de-en": {
+ "src": [
+ "Schöne Münchnerin 2018: Schöne Münchnerin 2018 in Hvar: Neun Dates",
+ "Von az, aktualisiert am 04.05.2018 um 11:11",
+ "Ja, sie will...",
+ "\"Schöne Münchnerin\" 2018 werden!",
+ "Am Nachmittag wartet erneut eine Überraschung auf unsere Kandidatinnen: sie werden das romantische Candlelight-Shooting vor der MY SOLARIS nicht alleine bestreiten, sondern an der Seite von Male-Model Fabian!",
+ "Hvar - Flirten, kokettieren, verführen - keine einfachen Aufgaben für unsere Mädchen.",
+ "Insbesondere dann, wenn in Deutschland ein Freund wartet.",
+ "Dennoch liefern die neun \"Schöne Münchnerin\"-Kandidatinnen beim Shooting mit People-Fotograf Tuan ab und trotzen Wind, Gischt und Regen wie echte Profis."
+ ],
+ "tgt": [
+ "The Beauty of Munich 2018: the Beauty of Munich 2018 in Hvar: Nine dates",
+ "From A-Z, updated on 04/05/2018 at 11:11",
+ "Yes, she wants to...",
+ "to become \"The Beauty of Munich\" in 2018!",
+ "In the afternoon there is another surprise waiting for our contestants: they will be competing for the romantic candlelight photo shoot at MY SOLARIS not alone, but together with a male-model Fabian!",
+ "Hvar with its flirting, coquetting, and seduction is not an easy task for our girls.",
+ "Especially when there is a boyfriend waiting in Germany.",
+ "Despite dealing with wind, sprays and rain, the nine contestants of \"The Beauty of Munich\" behaved like real professionals at the photo shoot with People-photographer Tuan."
+ ]
+ }
+}
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/test.source b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/test.source
new file mode 100644
index 0000000000000000000000000000000000000000..3eea3d95b8e1548803217cb4c69cc44358b1e9fb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/test.source
@@ -0,0 +1,20 @@
+UN Chief Says There Is No Military Solution in Syria Secretary-General Ban Ki-moon says his response to Russia's stepped up military support for Syria is that "there is no military solution" to the nearly five-year conflict and more weapons will only worsen the violence and misery for millions of people. The U.N. chief again urged all parties, including the divided U.N. Security Council, to unite and support inclusive negotiations to find a political solution. Ban told a news conference Wednesday that he plans to meet with foreign ministers of the five permanent council nations - the U.S., Russia, China, Britain and France - on the sidelines of the General Assembly's ministerial session later this month to discuss Syria.
+He expressed regret that divisions in the council and among the Syrian people and regional powers "made this situation unsolvable." Ban urged the five permanent members to show the solidarity and unity they did in achieving an Iran nuclear deal in addressing the Syria crisis. 8 Poll Numbers That Show Donald Trump Is For Real Some have tried to label him a flip-flopper. Others have dismissed him as a joke. And some are holding out for an implosion. But no matter how some Republicans are trying to drag Donald Trump down from atop the polls, it hasn't worked (yet).
+Ten of the last 11 national polls have shown Donald Trump's lead at double digits, and some are starting to ask seriously what it means for the real estate mogul's nomination chances. Of course, it's still early in the election cycle. None of this is to say that Trump is likely to win the Republican nomination. Pundits point out that at this time in 2011, Rick Perry's lead was giving way to a rising Herman Cain, neither of whom won even one state in the nomination process. And there are many reasons he would struggle in a general election. But outside groups like Jeb Bush's Super PAC and the economic conservative group Club for Growth are recognizing Trump's staying power and beginning to unload their dollars to topple him.
+Here are some recent poll numbers that suggest that the real estate mogul isn't just a passing phase: Trump's favorability ratings have turned 180 degrees. Right before Donald Trump announced his candidacy in mid-June, a Monmouth University poll showed only two in 10 Republicans had a positive view of the real estate mogul. By mid-July, it was 40 percent. In early August, it was 52 percent. Now, six in 10 Republicans have a favorable view of Donald Trump. Roughly three in 10 say they have a negative view. And these numbers hold up in early states. A Quinnipiac poll in Iowa last week found that 60 percent of Republicans there had a favorable view of Trump.
+Two-thirds of GOP voters would be happy with Trump as the nominee. In a CNN/ORC poll last week, 67 percent of Republicans said they would be either "enthusiastic" or "satisfied" if Trump were the nominee. Only two in 10 say they would be "upset" if he were the nominee. Only Ben Carson generates roughly the same level of enthusiasm as Trump (43 percent say they would be "enthusiastic" vs. 40 percent who say the same of Trump). The next closest in enthusiasm? Marco Rubio with only 21 percent.
+On the flip side, 47 percent of Republican voters say they would be "dissatisfied" or "upset" if establishment favorite Jeb Bush becomes the nominee. A majority of Republicans don't see Trump's temperament as a problem. While Donald Trump has been widely criticized for his bombast and insults, 52 percent of leaned Republican voters nationwide think that the real estate mogul has the right temperament to be president, according to Monday's ABC News/Washington Post poll. The same number holds in the first-in-the-nation caucus state of Iowa, where the same 52 percent of Republicans think he has the personality to be commander in chief, according to Quinnipiac last week.
+Still, 44 percent think he doesn't have the personality to serve effectively, and almost six in 10 independents say his temperament does not belong in the White House, according to ABC/Post. Republican voters are getting used to the idea. When they put on their pundit hats, Republican voters think Trump is for real. When asked who is most likely to win the GOP nomination, four in 10 said Trump was the best bet, according to a CNN/ORC poll out last week. That's a change from when four in 10 placed their money on Jeb Bush in late July. Full disclosure: GOP voters haven't had the clearest crystal ball in the past.
+At this time last cycle, four in 10 Republicans picked Rick Perry to win the nomination, vs. only 28 percent for eventual nominee Mitt Romney. Still, it shows that a plurality of GOP voters see Trump's campaign as plausible. Even if Republicans rallied around another candidate, Trump still beats almost everyone. Some pundits point out that the splintered field is likely contributing to Trump's lead, while anti-Trump support is be spread diffusely among more than a dozen other candidates. But a Monmouth University poll in early September shows that, in a hypothetical head-to-head matchup between Trump and most other Republican candidates, Trump almost always garners majority support.
+He leads Carly Fiorina by 13 points, Marco Rubio by 14 points, Walker by 15 points, Jeb Bush by 19 points, and, finally, Rand Paul, John Kasich and Chris Christie by 33 points each. He's in a dead heat with Ted Cruz. The only candidate who beats him? Ben Carson would lead the businessman by a wide 19 points in a hypothetical head-to-head. A bare majority of Donald Trump's supporters say they've made up their minds. A new CBS/NYT poll out on Tuesday shows that just more than half of voters who support Trump say they have locked in their votes. Obviously, a lot can happen to change that, and no one can really say they would never change their mind.
+46 percent said they are leaving the door open to switching candidates. Still, Trump's strongest competition at the moment is from fellow outsider neurosurgeon Ben Carson, but voters who say they have made up their minds are twice as likely to go for Trump. Six in 10 Republicans say they agree with Trump on immigration. Even since Donald Trump called immigrants from Mexico "rapists" in his campaign announcement speech two months ago, immigration has been front and center in the 2016 conversation. Some are worried that Trump's bombast will drive crucial Hispanic voters away from the Republican Party and damage rebranding efforts.
+But according to Monday's new ABC/Post poll, six in 10 Republicans say they agree with Trump on immigration issues. So as long as immigration remains in the spotlight, it seems Donald Trump will remain too. Frustration with government is climbing to new highs. Donald Trump and Ben Carson now account for roughly half of the support from Republican voters, largely due to their outsider status. Six in 10 Republicans in Monday's new ABC/Post poll say they want a political outsider over someone with government experience. And they are angry at Washington, too.
+A Des Moines Register/Bloomberg poll in Iowa from two weeks ago shows that three in four Iowa Republicans are frustrated with Republicans in Congress, with 54 percent "unsatisfied" and 21 percent "mad as hell." Jeremy Corbyn to make debut at Prime Minister's Questions Since his election, Mr Corbyn's debut at PMQs has been keenly awaited New Labour leader Jeremy Corbyn is to make his debut at Prime Minister's Questions later, taking on David Cameron for the first time.
+Mr Corbyn will rise to ask the first of his six allotted questions shortly after midday, with his performance likely to be closely scrutinised by the media and Labour MPs. He has called for "less theatre and more facts" at the weekly showpiece. He has also said he could skip some sessions, leaving them to colleagues. The encounter will be the first parliamentary test of Mr Corbyn's leadership, coming after his appointment of a shadow cabinet and his speech to the TUC annual congress on Tuesday.
+Meanwhile, the Labour leader's decision to stand in silence during the singing of the national anthem at a service on Tuesday to mark the 75th anniversary of the Battle of Britain has attracted criticism from a number of Tory MPs and is the focus of several front page stories in the newspapers. Mr Corbyn's decision not to sing the national anthem has attracted attention A spokesman for Mr Corbyn said he had "stood in respectful silence" and did recognise the "heroism of the Royal Air Force in the Battle of Britain."
+But a member of Mr Corbyn's shadow cabinet, Owen Smith, told BBC Two's Newsnight programme he would have advised the Labour leader to sing the national anthem "irrespective" of his belief that the monarchy should be abolished. Nearly a dozen shadow ministers have refused to serve in Mr Corbyn's top team, citing differences over the economy, defence and foreign affairs, while less than a sixth of the parliamentary party originally backed him as leader. BBC political correspondent Robin Brant says policy differences are also "stacking up" within Labour following Mr Corbyn's appointment over its position on the European Union and the government's cap on benefits.
+Mr Corbyn told the TUC conference Labour was putting forward amendments to remove the whole idea of a cap altogether. Hours later Mr Smith, the shadow work and pensions secretary, said the party was "very clear" that it was only opposing government plans to reduce the level of cap from £26,000 to £23,000. Mr Corbyn will be the fifth Labour leader that David Cameron has faced across the despatch box over the past decade since he became Tory leader. The Labour leader, who has promised a different approach to politics, says he has "crowd sourced" ideas for questions to ask Mr Cameron and has been given more than 30,000 suggestions.
+The Islington North MP has said PMQs is too confrontational and that he will refrain from both "repartee" and trading barbs, instead vowing to focus on serious issues such as poverty, inequality and the challenges facing young people. Mr Corbyn has said that Angela Eagle, the shadow business secretary, will deputise for him at PMQs when he does not attend - for instance when Mr Cameron is travelling abroad. He has also floated the idea of allowing other colleagues to take the floor on occasion, saying he had approached the Commons Speaker John Bercow to discuss the issue.
+When he became leader in 2005, Mr Cameron said he wanted to move away from the "Punch and Judy" style of politics often associated with PMQs but admitted some years later that he had failed. Since it was first televised in 1990, PMQs has been seen as a key barometer of a leader's judgement, their command of the Commons and their standing among their fellow MPs although critics have argued it has become a caricature and is in need of far-reaching reforms. 'Shot in Joburg': Homeless youth trained as photographers Downtown Johannesburg is a tough place to be homeless.
+But one group of former street children have found a way to learn a skill and make a living. "I was shot in Joburg" is a non-profit studio that teaches homeless youngsters how to take photographs of their neighbourhood and make a profit from it. BBC News went to meet one of the project's first graduates. JD Sports boss says higher wages could hurt expansion JD Sports Executive Chairman Peter Cowgill says a higher minimum wage for UK workers could mean "more spending power in the pockets of potential consumers." But that spending power is unlikely to outweigh the higher labour costs at his firm, he says.
+The costs could hit JD Sports' expansion plans, he added, which could mean fewer extra jobs. Thanasi Kokkinakis backed by Tennis Australia president Steve Healy Thanasi Kokkinakis deserves kudos rather than criticism for his behaviour. Thanasi Kokkinakis has been the collateral damage in the recent storm around his friend Nick Kyrgios and deserves kudos rather than criticism for his own behaviour, according to Tennis Australia president Steve Healy.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/test.target b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/test.target
new file mode 100644
index 0000000000000000000000000000000000000000..8c88fd05326fcfe503ef7eba77921c182758a290
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/test.target
@@ -0,0 +1,20 @@
+Șeful ONU declară că nu există soluții militare în Siria Secretarul General Ban Ki-moon afirmă că răspunsul său la suportul militar al Rusiei pentru Siria este că „nu există o soluție militară” la conflictul care durează de aproape cinci ani iar mai multe arme nu ar face decât să agraveze violența și suferința a milioane de oameni. Șeful ONU a solicitat din nou tuturor părților, inclusiv Consiliului de securitate ONU divizat să se unifice și să susțină negocierile pentru a găsi o soluție politică. Ban a declarat miercuri în cadrul unei conferințe că intenționează să se întâlnească luna aceasta cu miniștrii de externe din cinci țări permanent prezente în consiliu - SUA, Rusia, China, Anglia și Franța - pe marginea sesiunii ministeriale a Adunării Generale pentru a discuta despre Siria.
+Ban și-a exprimat regretul că divizările în consiliu și între poporul sirian și puterile regionale „au făcut această situație de nerezolvat”. Ban le-a cerut celor cinci membri permanenți să dea dovadă de solidaritatea și unitatea arătate atunci când au reușit să încheie un acord referitor la armele nucleare ale Iranului, abordând astfel criza din Siria. 8 cifre din sondaje care arată că Donald Trump are șanse reale Unii au încercat să îl eticheteze ca politician „flip-flop”. Alții l-au numit o glumă. Iar alții așteaptă implozia. Însă indiferent de modul în care unii republicani încearcă să îl dărâme pe Donald Trump din vârful sondajelor, nu a funcționat (încă).
+Zece din ultimele 11 sondaje naționale au arătat că Donald Trump conduce cu un procent din două cifre iar unele voci încep să se întrebe serios ce înseamnă acest lucru pentru șansele de numire ale mogulului imobiliar. Desigur, este încă prematur. Nimic din toate acestea nu spune că Trump va câștiga cursa pentru nominalizarea republicanilor. Pundits arată că, în aceeași perioadă a anului 2011, avansul lui Rick Perry îi făcea loc lui Herman Cain în sondaje, dar niciunul dintre ei nu a câștigat în vreun stat în cursa de nominalizare. Iar motivele pentru care s-ar lupta din greu la alegerile generale sunt numeroase. Însă grupurile din exterior precum Super PAC al lui Jeb Bush și grupul conservator economic Club for Growth admit puterea lui Trump și încep să îl susțină cu bani.
+În continuare vă prezentăm câteva cifre din sondaje recente care sugerează că mogulul imobiliar nu este doar ceva trecător: Cifrele care indică susținerea față de Trump s-au întors la 180 grade. Chiar înainte ca Donald Trump să își anunțe candidatura, la mijlocul lui iunie, un sondaj realizat de Universitatea din Monmouth arăta că doar doi din 10 republicani aveau o părere pozitivă despre mogulul imobiliar. Până la mijlocul lui iulie, procentul a urcat la 40%. La începutul lui august, era 52%. În prezent, șase din 10 republicani au o părere favorabilă despre Donald Trump. Aproximativ trei din 10 declară că au o părere negativă. Aceste cifre se mențin. Un sondaj realizat săptămâna trecută de Quinnipiac în Iowa a concluzionat că 60% dintre republicanii din regiune au o părere favorabilă despre Trump.
+Două treimi dintre alegătorii GOP ar fi fericiți dacă Trump ar câștiga cursa pentru nominalizare. Într-un sondaj realizat săptămâna trecută de CNN/ORC, 67% dintre republicani au declarat că ar fi „entuziasmați” sau „mulțumiți” dacă Trump ar câștiga cursa pentru nominalizare. Doar doi din 10 declară că ar fi „supărați” dacă Trump ar câștiga cursa pentru nominalizare. Doar Ben Carson generează aproximativ același nivel de entuziasm ca Trump (43% declară că ar fi „entuziasmați” față de 40% care declară același lucru despre Trump). Cel mai aproape în ceea ce privește entuziasmul? Marco Rubio, cu doar 21%.
+De partea cealaltă, 47% dintre alegătorii republicani afirmă că ar fi „nemulțumiți” sau „supărați” dacă favoritul Jeb Bush câștigă cursa pentru nominalizare. Majoritatea republicanilor nu consideră temperamentul lui Trump o problemă. Deși Donald Trump a fost puternic criticat pentru insultele aduse și stilul său bombastic, 52% dintre alegătorii republicani la nivel național consideră că mogulul imobiliar are temperamentul potrivit pentru a fi președinte, conform sondajului realizat luni de ABC News/Washington Post. Regăsim aceleași cifre în statul Iowa, unde tot 52% dintre republicani cred că Trump are personalitatea potrivită pentru a fi conducător, conform sondajului realizat săptămâna trecută de Quinnipiac.
+Totuși, 44% sunt de părere că nu are personalitatea necesară pentru a acționa eficient și aproape șase din 10 independenți afirmă că temperamentul său nu are ce căuta la Casa Albă, conform ABC/Post. Alegătorii republicani se obișnuiesc cu ideea. Atunci când iau atitudinea de intelectuali, alegătorii republicani consideră că Trump este autentic. Conform unui sondaj realizat săptămâna trecută de CNN/ORC, la întrebarea cine are cele mai multe șanse să câștige cursa pentru nominalizare GOP, patru din 10 au declarat că Trump. Situația s-a schimbat față de finalul lui iulie, când patru din 10 ar fi pariat pe Jeb Bush. Informare completă: în trecut, alegătorii GOP nu au citit foarte bine viitorul.
+În aceeași perioadă a ultimelor alegeri, patru din 10 republicani l-au ales pe Rick Perry în cursa pentru nominalizare, față de doar 28% pentru Mitt Romney. Însă, aceste cifre arată că majoritatea alegătorilor GOP consideră plauzibilă campania lui Trump. Chiar dacă republicanii sau repliat spre un alt candidat. Trump încă se află în fruntea tuturor. Unele voci spun că situația divizată va contribui probabil la victoria lui Trump, în timp ce susținerea contra lui Trump se va împărți la mai mult de doisprezece candidați. Însă un sondaj derulat la începutul lui septembrie de Universitatea din Monmouth arată că, în situația ipotetică a unei colaborări între Trump și majoritatea celorlalți candidați republicani, aproape întotdeauna Trump va beneficia de susținerea majoritară.
+Trump se află la distanță de 13 puncte de Carly Fiorina, la 14 puncte de Marco Rubio, la 15 puncte de Walker, la 19 puncte de Jeb Bush și, în cele din urmă, la câte 33 de puncte față de Rand Paul, John Kasich și Chris Christie. Este aproape la egalitate cu Ted Cruz. Singurul candidat care îl învinge? Ben Carson l-ar învinge pe omul de afaceri cu 19 puncte într-o confruntare ipotetică de unu la unu. Majoritatea susținătorilor lui Donald Trump declară că s-au decis. Un nou sondaj realizat marți de CBS/NYT arată că peste jumătate dintre alegătorii care îl susțin pe Trump declară că nu își schimbă opțiunea de vot. Evident, se pot întâmpla multe în acest sens și nimeni nu poate spune că aceștia nu se vor răzgândi niciodată.
+46% afirmă că lasă portița deschisă posibilității de a-și schimba opțiunea. Cu toate acestea, cel mai important adversar al lui Trump este în prezent neurochirurgul Ben Carson, însă este de două ori mai probabil ca alegătorii care declară că s-au decis să voteze cu Trump. Șase din 10 republicani afirmă că sunt de acord cu Trump în problema imigrării. De când Donald Trump i-a numit pe imigranții din Mexic „violatori” în discursul de deschidere a campaniei sale, în urmă cu două luni, imigrarea a fost subiectul central în campania pentru 2016. Unii sunt îngrijorați că stilul bombastic al lui Trump va duce la o scindare între alegătorii hispanici importanți și Partidul Republican și va prejudicia eforturile de rebranding.
+Însă, conform sondajului realizat luni de ABC/Post, șase din 10 republicani afirmă că sunt de acord cu Trump în problema imigrării. Așa că, se pare că atâta timp cât problema imigrării rămâne în lumina reflectoarelor, la fel va rămâne și Doland Trump. Frustrarea față de autorități atinge noi culmi. Donald Trump și Ben Carson sunt acum susținuți de aproape jumătate dintre alegătorii republicani, în mare parte datorită statutului lor de outsideri. Conform sondajului realizat luni de ABC/Post, șase din 10 republicani afirmă că preferă un outsider politic în detrimentul cuiva cu experiență în guvernare. Oamenii sunt de asemenea supărați pe autoritățile de la Washington.
+Un sondaj derulat în urmă cu două săptămâni în Iowa de către Des Moines Register/Bloomberg arată că trei din patru republicani din Iowa sunt frustrați de prestația republicanilor din COngres, 54% declarându-se „nemulțumiți” iar 21% „nervoși la culme”. Jeremy Corbyn își face debutul la Prime Minister's Questions Încă de la alegerea sa, debutul domnului Corbyn la PMQs a fost îndelung așteptat Noul lider al Partidului Laburist, Jeremy Corbyn, își va face mai târziu debutul la Prime Minister's Questions, confruntându-se pentru prima dată cu David Cameron.
+Dl Corbyn va adresa primele dintre cele șase întrebări la care are dreptul la scurt timp după prânz; prestația sa va fi probabil analizată îndeaproape de mass-media și parlamentarii laburiști. În cadrul aparițiilor săptămânale, el a cerut „mai puțin teatru și mai multe fapte”. A declarat de asemenea că poate renunța la câteva participări și că le cedează colegilor săi. Confruntarea va fi primul test parlamentar al Dl Corbyn în poziție de lider, venind după ce a numit un „cabinet fantomă” și după discursul pe care l-a ținut marți la congresul anual TUC.
+Între timp, decizia liderului Partidului laburist de a păstra tăcerea la rostirea imnului național în cadrul unei slujbe ținute marți cu ocazia aniversării a 75 de ani de la Bătălia Angliei a atras critici din partea unor parlamentari conservatori și a ținut prima pagină a ziarelor. Decizia domnului Corbyn de a nu cânta imnul național a atras atenția Un purtător de cuvânt al Dl Corbyn a declarat că acesta „a păstrat tăcerea în mod respectuos” și a recunoscut „eroismul Forțelor aeriene britanice în Bătălia Angliei.”
+Însă un membru al cabinetului fantomă al Dl Corbyn, Owen Smith, a declarat pentru emisiunea Two's Newsnight transmisă de BBC că i-ar fi recomandat liderului laburist să cânte imnul național „indiferent” de credința sa că monarhia ar trebui abolită. În jur de doisprezece miniștri din cabinetul fantomă au refuzat să facă parte din echipa de frunte a Dl Corbyn, argumentând prin diferențe de opinie legate de economie, apărare și externe, în timp ce mai puțin de o șesime din partidul parlamentar l-a susținut ca lider. Corespondentul politic al BBC, Robin Brant, declară că diferențele de politică „se cumulează” în Partidul Laburist după numirea domnului Corbyn referitor la poziția sa față de Uniunea Europeană și limita de beneficii.
+Dl Corbyn a declarat la conferința TUC că Partidul Laburist va aduce modificări prin care se va elimina integral ideea limitării. Câteva ore mai târziu, Dl Smith, Ministrul Muncii și Pensiilor, a declarat că partidul „este foarte clar” în opoziția exclusivă față de planurile guvernului de a reduce nivelul „cap” de la 26.000 lire la 23.000 lire. Dl Corbyn va fi al cincilea lider laburist cu care se confruntă David Cameron la tribună în ultimul deceniu, de când a preluat conducerea Partidului Conservator. Liderul laburist, care a promis o abordare diferită a politicii, spune că are idei „din surse externe” pentru întrebări pe care să i le adreseze Domnului Cameron și că a primit peste 30.000 de sugestii.
+Parlamentarul Islington North a afirmat că PMQs implică un nivel de confruntare prea înalt și că se va abține de la replici și atacuri, angajându-se să se concentreze în schimb pe probleme serioase precum sărăcia, inegalitatea și provocările cu care se confruntă tinerii. Dl Corbyn a declarat că Angela Eagle, Ministrul de finanțe, îi va ține locul la PMQs atunci când el nu poate participa - de exemplu atunci când Dl Cameron se deplasează în străinătate. A exprimat de asemenea ideea că va permite altor colegi să ia cuvântul ocazional, spunând că l-a abordat pe Președintele Camerei Deputaților, John Bercow, pentru a discuta acest aspect.
+În 2005, când a preluat conducerea, Dl Cameron a declarat că dorește să renunțe la stilul politic „Punch and Judy” asociat adesea cu PMQs însă a recunoscut câțiva ani mai târziu că nu a reușit în demersul său. De la prima transmisie, în 1990, PMQs a fost considerată un barometru cheie al raționamentului unui lider, al modului în care acesta conduce Camera Deputaților și a poziției sale în rândul colegilor parlamentari, deși criticii afirmă a ca devenit o caricatură și că are nevoie de o reformare profundă. „Cadru în Joburg”: Tineri fără adăpost beneficiază de cursuri de fotografie Este dificil să fii un om fără adăpost în Johannesburg.
+Însă un grup de oameni care au trăit pe străzi în copilărie au găsit un mod de a învăța o meserie și de a-și câștiga traiul. „I was shot în Joburg” este un studio non-profit care îi învață pe tinerii fără adăpost să facă fotografii ale zonelor în care trăiesc și să câștige bani din asta. BBC News s-a întâlnit cu unul dintre primii absolvenți ai proiectului. Șeful JD Sports spune că salariile mai mari ar putea dăuna extinderii Președintele JD Sports, Peter Cowgill, declară că o creștere a salariului minim în Marea Britanie ar putea însemna „o putere de cumpărare mai mare în buzunarele potențialilor consumatori.” Este însă puțin probabil ca respectiva putere de cumpărare să depășească costurile mai mari pentru forța de muncă în cadrul firmei, afirmă el.
+Costurile ar putea avea impact asupra planurilor de extindere ale JD Sports, a adăugat el, ceea ce ar putea însemna mai puține locuri de muncă noi. Thanasi Kokkinakis susținut de președintele Tennis Australia, Steve Healy Thanasi Kokkinakis ar merita să fie lăudat și nu criticat pentru comportamentul său. Thanasi Kokkinakis a fost victimă colaterală în „furtuna” creată în jurul prietenului său, Nick Kyrgios, iar comportamentul său merită mai degrabă cuvinte de laudă și nu critică, în opinia președintelui Tennis Australia, Steve Healy.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/train.len b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/train.len
new file mode 100644
index 0000000000000000000000000000000000000000..33ce003c8ae3139914a389a714812a2ab13aece4
Binary files /dev/null and b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/train.len differ
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/train.source b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/train.source
new file mode 100644
index 0000000000000000000000000000000000000000..d77722d4a57002e81b832fc94a326fc4acebb0d8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/train.source
@@ -0,0 +1,11 @@
+Corrections to votes and voting intentions: see Minutes Assignment conferred on a Member: see Minutes Membership of committees and delegations: see Minutes Decisions concerning certain documents: see Minutes Forwarding of texts adopted during the sitting: see Minutes Dates for next sittings: see Minutes
+Membership of Parliament: see Minutes Approval of Minutes of previous sitting: see Minutes Membership of Parliament: see Minutes Verification of credentials: see Minutes Documents received: see Minutes Written statements and oral questions (tabling): see Minutes Petitions: see Minutes Texts of agreements forwarded by the Council: see Minutes Action taken on Parliament's resolutions: see Minutes Agenda for next sitting: see Minutes Closure of sitting (The sitting was closed at 7.45 p.m.)
+Election of Vice-Presidents of the European Parliament (deadline for submitting nominations): see Minutes (The sitting was suspended at 12.40 p.m. and resumed at 3.00 p.m.) Election of Quaestors of the European Parliament (deadline for submitting nominations): see Minutes (The sitting was suspended at 3.25 p.m. and resumed at 6.00 p.m.) Agenda for next sitting: see Minutes Closure of sitting (The sitting was closed at 6.15 p.m.) Opening of the sitting (The sitting was opened at 9.35 a.m.) Documents received: see Minutes Approval of Minutes of previous sitting: see Minutes Membership of Parliament: see Minutes
+Membership of committees (deadline for tabling amendments): see Minutes (The sitting was suspended at 7 p.m. and resumed at 9 p.m.) Agenda for next sitting: see Minutes Closure of sitting (The sitting was suspended at 23.25 p.m.) Documents received: see Minutes Communication of Council common positions: see Minutes (The sitting was suspended at 11.35 a.m. and resumed for voting time at noon) Approval of Minutes of previous sitting: see Minutes Committee of Inquiry into the crisis of the Equitable Life Assurance Society (extension of mandate): see Minutes
+Announcement by the President: see Minutes 1. Membership of committees (vote) 2. Amendment of the ACP-EC Partnership Agreement (vote) 4. Certification of train drivers operating locomotives and trains on the railway system in the Community (vote) 6. Law applicable to non-contractual obligations ("ROME II") (vote) 8. Seventh and eighth annual reports on arms exports (vote) Corrections to votes and voting intentions: see Minutes Membership of committees and delegations: see Minutes Request for waiver of parliamentary immunity: see Minutes Decisions concerning certain documents: see Minutes
+Written statements for entry
+Written statements for entry in the register (Rule 116): see Minutes Forwarding of texts adopted during the sitting: see Minutes Dates for next sittings: see Minutes Adjournment of the session I declare the session of the European Parliament adjourned. (The sitting was closed at 1 p.m.) Approval of Minutes of previous sitting: see Minutes Membership of Parliament: see Minutes Request for the defence of parliamentary immunity: see Minutes Appointments to committees (proposal by the Conference of Presidents): see Minutes Documents received: see Minutes Texts of agreements forwarded by the Council: see Minutes
+Action taken on Parliament's resolutions: see Minutes Oral questions and written statements (tabling): see Minutes Written statements (Rule 116): see Minutes Agenda: see Minutes 1. Appointments to parliamentary committees (vote): see Minutes Voting time Agenda for next sitting: see Minutes Closure of sitting (The sitting was closed at 12 midnight) Opening of the sitting (The sitting was opened at 09.05) Documents received: see Minutes Approval of Minutes of previous sitting: see Minutes 1. Protection of passengers against displaced luggage (vote) 2.
+Approval of motor vehicles with regard to the forward field of vision of the driver (vote) 3. EC-Korea Agreement on scientific and technological cooperation (vote) 4. Mainstreaming sustainability in development cooperation policies (vote) 5. Draft Amending Budget No 1/2007 (vote) 7. EC-Gabon Fisheries Partnership (vote) 10. Limitation periods in cross-border disputes involving personal injuries and fatal accidents (vote) 12. Strategy for a strengthened partnership with the Pacific Islands (vote) 13. The European private company statute (vote) That concludes the vote.
+Corrections to votes and voting intentions: see Minutes Assignment conferred on a Member: see Minutes Membership of committees and delegations: see Minutes Decisions concerning certain documents: see Minutes Forwarding of texts adopted during the sitting: see Minutes Dates for next sittings: see Minutes
+Written statements for entry
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/train.target b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/train.target
new file mode 100644
index 0000000000000000000000000000000000000000..f18d80d3d47d6cae112d7f705effdb26beeb1efe
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/train.target
@@ -0,0 +1,11 @@
+Corectările voturilor şi intenţiile de vot: a se vedea procesul-verbal Misiune încredinţată unui deputat: consultaţi procesul-verbal Componenţa comisiilor şi a delegaţiilor: a se vedea procesul-verbal Decizii privind anumite documente: a se vedea procesul-verbal Transmiterea textelor adoptate în cursul prezentei şedinţe: a se vedea procesul-verbal Calendarul următoarelor şedinţe: a se vedea procesul-verbal
+Componenţa Parlamentului: a se vedea procesul-verbal Aprobarea procesului-verbal al şedinţei precedente: a se vedea procesul-verbal Componenţa Parlamentului: a se vedea procesul-verbal Verificarea prerogativelor: a se vedea procesul-verbal Depunere de documente: a se vedea procesul-verbal Declaraţii scrise şi întrebări orale (depunere): consultaţi procesul-verbal Petiţii: a se vedea procesul-verbal Transmiterea de către Consiliu a textelor acordurilor: a se vedea procesul-verbal Cursul dat rezoluţiilor Parlamentului: a se vedea procesul-verbal Ordinea de zi a următoarei şedinţe: a se vedea procesul-verbal Ridicarea şedinţei (Se levanta la sesión a las 19.45 horas)
+Alegerea vicepreşedinţilor Parlamentului European (termenul de depunere a candidaturilor): consultaţi procesul-verbal (Die Sitzung wird um 12.40 Uhr unterbrochen und um 15.00 Uhr wiederaufgenommen). Alegerea chestorilor Parlamentului European (termenul de depunere a candidaturilor): consultaţi procesul-verbal (Die Sitzung wird um 15.25 Uhr unterbrochen und um 18.00 Uhr wiederaufgenommen). Ordinea de zi a următoarei şedinţe: a se vedea procesul-verbal Ridicarea şedinţei (Die Sitzung wird um 18.15 Uhr geschlossen.) Deschiderea şedinţei (Die Sitzung wird um 9.35 Uhr eröffnet.) Depunerea documentelor: a se vedea procesul-verbal Aprobarea procesului-verbal al şedinţei precedente: a se vedea procesul-verbal Componenţa Parlamentului: a se vedea procesul-verbal
+Componenţa comisiilor (termenul de depunere a amendamentelor): consultaţi procesul-verbal (La seduta, sospesa alle 19.00, è ripresa alle 21.00) Ordinea de zi a următoarei şedinţe: a se vedea procesul-verbal Ridicarea şedinţei (Die Sitzung wird um 23.25 Uhr geschlossen.) Depunerea documentelor: a se vedea procesul-verbal Comunicarea poziţiilor comune ale Parlamentului: a se vedea procesul-verbal (La séance, suspendue à 11h35 dans l'attente de l'Heure des votes, est reprise à midi) Aprobarea procesului-verbal al şedinţei precedente: a se vedea procesul-verbal Comisia de anchetă privind criza societăţii de asigurări "Equitable Life” (prelungirea mandatului): consultaţi procesul-verbal
+Comunicarea Preşedintelui: consultaţi procesul-verbal 1. Componenţa comisiilor (vot) 2. Modificarea Acordului de parteneriat ACP-CE ("Acordul de la Cotonou”) (vot) 4. Certificarea mecanicilor de locomotivă care conduc locomotive şi trenuri în sistemul feroviar comunitar (vot) 6. Legea aplicabilă obligaţiilor necontractuale ("Roma II”) (vot) 8. Al şaptelea şi al optulea raport anual privind exportul de armament (vot) Corectările voturilor şi intenţiile de vot: a se vedea procesul-verbal Componenţa comisiilor şi a delegaţiilor: a se vedea procesul-verbal Cerere de ridicare a imunităţii parlamentare: consultaţi procesul-verbal Decizii privind anumite documente: a se vedea procesul-verbal
+Declaraţii scrise înscrise
+Declaraţii scrise înscrise în registru (articolul 116 din Regulamentul de procedură): a se vedea procesul-verbal Transmiterea textelor adoptate în cursul prezentei şedinţe: a se vedea procesul-verbal Calendarul următoarelor şedinţe: a se vedea procesul-verbal Întreruperea sesiunii Dichiaro interrotta la sessione del Parlamento europeo. (La seduta è tolta alle 13.00) Aprobarea procesului-verbal al şedinţei precedente: a se vedea procesul-verbal Componenţa Parlamentului: a se vedea procesul-verbal Cerere de apărare a imunităţii parlamentare: consultaţi procesul-verbal Numiri în comisii (propunerea Conferinţei preşedinţilor): consultaţi procesul-verbal Depunerea documentelor: a se vedea procesul-verbal Transmiterea de către Consiliu a textelor acordurilor: a se vedea procesul-verbal
+Continuări ale rezoluţiilor Parlamentului: consultaţi procesul-verbal Declaraţii scrise şi întrebări orale (depunere): consultaţi procesul-verbal Declaraţii scrise (articolul 116 din Regulamentul de procedură) Ordinea de zi: a se vedea procesul-verbal 1. Numiri în comisiile parlamentare (vot): consultaţi procesul-verbal Timpul afectat votului Ordinea de zi a următoarei şedinţe: a se vedea procesul-verbal Ridicarea şedinţei (La seduta è tolta alle 24.00) Deschiderea şedinţei (The sitting was opened at 09.05) Depunerea documentelor: a se vedea procesul-verbal Aprobarea procesului-verbal al şedinţei precedente: a se vedea procesul-verbal 1. Protecţia pasagerilor împotriva deplasării bagajelor (vot) 2.
+Omologarea vehiculelor cu motor cu privire la câmpul de vizibilitate înainte al conducătorului auto (vot) 3. Acordul CE-Coreea de cooperare ştiinţifică şi tehnologică (vot) 4. Integrarea durabilităţii în politicile de cooperare pentru dezvoltare (vot) 5. Proiect de buget rectificativ nr.1/2007 (vot) 7. Acordul de parteneriat în domeniul pescuitului între Comunitatea Europeană şi Republica Gaboneză (vot) 10. Termenele de prescripţie aplicabile în cadrul litigiilor transfrontaliere cu privire la vătămările corporale şi accidentele mortale (vot) 12. Relaţiile UE cu insulele din Pacific: Strategie pentru un parteneriat consolidat (vot) 13. Statutul societăţii private europene (vot) Damit ist die Abstimmungsstunde beendet.
+Corectările voturilor şi intenţiile de vot: a se vedea procesul-verbal Misiune încredinţată unui deputat: consultaţi procesul-verbal Componenţa comisiilor şi a delegaţiilor: a se vedea procesul-verbal Decizii privind anumite documente: a se vedea procesul-verbal Transmiterea textelor adoptate în cursul prezentei şedinţe: a se vedea procesul-verbal Calendarul următoarelor şedinţe: a se vedea procesul-verbal
+Declaraţii scrise înscrise
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/val.len b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/val.len
new file mode 100644
index 0000000000000000000000000000000000000000..897314a960b28d927b597805693e63f9de71d903
Binary files /dev/null and b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/val.len differ
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/val.source b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/val.source
new file mode 100644
index 0000000000000000000000000000000000000000..c895d0ae247e2bc529ae4f94be6079cd36f50fa2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/val.source
@@ -0,0 +1,16 @@
+Brazil's Former Presidential Chief-of-Staff to Stand Trial A federal judge on Tuesday accepted the charges filed against Brazil's former presidential chief of staff for his alleged involvement in a massive corruption scheme at state-owned oil company Petrobras. The federal prosecutor's office said Jose Dirceu will face trial on the corruption, racketeering and money laundering charges filed earlier this month. Fourteen other people will also be tried, including Joao Vaccari Neto, the former treasurer of Brazil's governing Workers' Party and Renato de Souza Duque, Petrobras' former head of corporate services.
+Dirceu is the most senior member of the ruling Workers' Party to be taken into custody in connection with the scheme. Dirceu served as former President Luiz Inacio Lula da Silva's chief of staff between 2003 and 2005. He was arrested early August in his home, where he already was under house arrest serving an 11-year sentence for his involvement in a cash-for-votes scheme in Congress more than 10 years ago. Prosecutors have said that Dirceu masterminded the kickback scheme at Petrobras, accepted bribes while in office and continued to receive payments from contractors after he was jailed in late 2013 for the vote-buying scandal.
+According to prosecutors, the scheme at Petrobras involved roughly $2 billion in bribes and other illegal funds. Some of that money was allegedly funneled back to campaign coffers of the ruling party and its allies. It also allegedly included the payment of bribes to Petrobras executives in return for inflated contracts. 'Miraculous' recovery for Peshawar massacre schoolboy A teenager paralysed after being shot four times in Pakistan's deadliest terror attack has made a "miraculous" recovery following treatment in the UK. Muhammad Ibrahim Khan, 13, had been told by doctors in Pakistan that he would never walk again.
+At least 140 people, mostly children, were killed when gunmen stormed Peshawar's Army Public School last December. Muhammad, who arrived in London last month for surgery, is being discharged from hospital later. Exactly nine months ago, on an ordinary Tuesday morning, Muhammad sat in his first aid class listening to his teachers intently. At the same time seven gunmen disguised in security uniforms were entering the Army Public School. They were strapped with explosives and had one simple mission in mind: Kill every man, woman and child they came across. "I can't forget what happened that day," Muhammad says with a severe stare.
+We were sitting in the auditorium, we were asking questions... and then we heard heavy gunfire outside. The terrorists moved inside and they started killing - our teacher was burned alive. Muhammad described pulling four other pupils out of the auditorium as the carnage unfolded. He said he then heard his friend, Hamza calling to him. He said, 'oh brother save me'. I held his hand. That's when I was shot in the back, and he was shot in the head. Most of the people killed in the attack were pupils Hamza died in Muhammad's arms. Muhammad recalled blacking out after that, and the next thing he knew he was in a hospital bed, paralysed from the waist down.
+Doctors in Peshawar in northern Pakistan, and then Rawalpindi, close to the capital, told his family there was no treatment, and he would never walk again. "Seeing him I felt like my soul had left my body," says Muhammad's father, Sher Khan Those nine months were the hardest in my life. But Mr Khan and his wife, Sherbano, refused to believe that their cricket-mad son would never be able to use his legs again. They campaigned, and appealed for help on Pakistani TV, gaining the support of high profile people such as cricketer turned politician Imran Khan.
+Finally, they were able to raise the funds to bring Muhammad to the UK and provide him with treatment at London's private Harley Street Clinic. Consultant neurosurgeon Irfan Malik described Muhammad as "terrified" when he first arrived at the hospital. "He'd spent the last [few] months lying on a bed, unable to move side to side," says Mr Malik. He was weak, he had a pressure sore on his back. He wasn't in great shape. A vertebra at the base of Muhammad's spine was destroyed Muhammad was shot in his shoulder, his hip, and his back during the attack, damaging his lower spine - leading to paralysis.
+But during six hours of surgery, Mr Malik and his team were able to reattach nerve endings and reconstruct the damaged part of the spine. Even Mr Malik was surprised at what happened next. Exactly one week after the surgery Muhammad stood up and started taking steps and walking. We were not expecting to get that sort of excellent result. That was miraculous," he says. Less than two weeks after his operation, Muhammad is ready to leave hospital and start the long road to recovery. Muhammad has defied the odds and started to walk again He says he wants to build his strength and continue his education in the UK. But he says he is determined to return to Pakistan, join the army and help fight terrorism.
+"I feel like I have a second chance at life," he says as he shows off pictures he's drawn of guns scribbled out next to school books and pens Muhammad grows physically stronger every day but the psychological trauma he continues to endure is unimaginable. "My anger is not diminishing" he says. In my school little kids were killed. What was their crime? His mother, wiping a tear from her eye, caressed his head and said: "I can see my son walking again." He'll be able to get on with his normal life. 'Super Voice' 4G service from Three offers better signal Three is making use of a lower frequency 4G spectrum that can travel more widely
+Mobile phone provider Three has launched a UK service it says will improve reception inside buildings and in rural black spots. Its 4G Super Voice enables customers to make calls and send texts using a lower frequency spectrum. Other networks are looking into introducing the technology, known as Voice Over Long-Term Evolution (VoLTE). It currently works on only the Samsung Galaxy S5, but recent iPhone handsets will be added in the coming months. Three said up to 5.5 million customers would have access to the service by 2017.
+Chief technology officer Bryn Jones said: "By the end of the year, one million of our customers will have access to better indoor coverage and be able to use their phones in more places than ever before." Stars prepare for panto season Pantomime season is big business for theatres up and down the UK, with many getting ready for this year's season now. Some of the biggest names in showbusiness now take part in the yuletide theatre. Matthew Kelly and Hayley Mills will be appearing in Cinderella - one as an ugly sister, the other as fairy godmother. They reveal their panto secrets to BBC Breakfast. Steven Wilson: 'If I don't do anything, I feel this creeping guilt'
+Steven Wilson was recently the big winner at the Progressive Music Awards Steven Wilson is often dubbed the hardest working musician in the world of progressive rock. The multi-talented musician won three prizes at this month's Progressive Music Awards in London, including album of the year for Hand. The Guardian's five-star review called it "a smart, soulful and immersive work of art." Since the 1980s, Wilson has been the driving force in a number of musical projects, the best known of which is the rock band Porcupine Tree. Now, ahead of two sell-out shows at the Royal Albert Hall, Wilson is releasing a vinyl-only double LP, Transience, to showcase the "more accessible" side of his solo output.
+He tells the BBC about his love of vinyl, his busy schedule and explains how comic actor Matt Berry came to be his support act. What does vinyl mean to you? I grew up at the very tail end of the vinyl era, and at the time, I remember, we couldn't wait for CD to come along because vinyl was so frustrating. You would buy the record, take it home, and it would have a scratch, and you would have to take it back again. I love CDs, and for some kinds of music - classical for example - it is better than vinyl. But the problem with the CD and digital downloads is that there's nothing you can really cherish or treasure. Owning vinyl is like having a beautiful painting hanging in your living room.
+It's something you can hold, pore over the lyrics and immerse yourself in the art work. I thought it was just a nostalgic thing, but it can't be if kids too young to remember vinyl are enjoying that kind of experience. Do you have a piece of vinyl that you treasure? The truth is I got rid of 100% of my vinyl in the 90s. All the vinyl I have is re-bought. I started off from the perspective that I wanted to recreate the collection I had when I was 15, but it's gone beyond that. The first record which I persuaded my parents to buy for me was Electric Light Orchestra's Out of the Blue.
+If I still had my original copy, it would have sentimental value, but, alas, it's in a charity shop somewhere. Steven Wilson hopes the album will be a doorway for potential new fans Why release your new compilation Transience on vinyl? It was originally conceived as an idea for Record Store Day, but we missed the boat on that. My record company had suggested I put together some of my shorter, more accessible songs. I got a bit obsessed by the idea to make something like "an introduction to Steven Wilson," and I was committed to it being a vinyl-only release. Anyone who buys the vinyl does also get a high-resolution download.
+Do you have a concern that the album won't show your work in a true light?
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/val.target b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/val.target
new file mode 100644
index 0000000000000000000000000000000000000000..178d85d71902c8104f7446c3b9b8880553b49ed0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/test_data/wmt_en_ro/val.target
@@ -0,0 +1,16 @@
+Fostul șef al cabinetului prezidențial brazilian este adus în fața instanței Marți, un judecător federal a acceptat acuzațiile aduse împotriva fostului șef al cabinetului prezidențial brazilian pentru presupusa implicare a acestuia într-o schemă masivă de corupție privind compania petrolieră de stat Petrobras. Biroul procurorului federal a declarat că Jose Dirceu va fi trimis în judecată pentru acuzațiile de corupție, înșelătorie și spălare de bani aduse în această lună. Alte paisprezece persoane vor fi judecate, printre acestea numărându-se Joao Vaccari Neto, fostul trezorier al Partidului Muncitorilor, aflat la putere în Brazilia, și Renato de Souza Duque, fostul președinte al serviciilor pentru întreprinderi ale Petrobras.
+Dirceu este cel mai vechi membru al Partidului Muncitorilor aflat la guvernare luat în custodie pentru legăturile cu această schemă. Dirceu a servit ca șef de cabinet al fostului președinte Luiz Inacio Lula da Silva între 2003 și 2005. A fost arestat la începutul lui august de acasă, unde deja se afla sub arest la domiciliu, cu o pedeapsă de 11 ani pentru implicarea într-o schemă de cumpărare a voturilor în Congres cu peste 10 ani în urmă. Procurorii au declarat că Dirceu a dezvoltat schema de luare de mită de la Petrobras, a acceptat mită în timp ce se afla în funcție și a continuat să primească plăți de la antreprenori după ce a fost închis la sfârșitul lui 2013 pentru scandalul voturilor cumpărate.
+Conform procurorilor, schema de la Petrobras a implicat aproximativ 2 miliarde de dolari sub formă de mită și alte fonduri ilegale. O parte din acei bani s-ar fi întors în fondul de campanie al partidului aflat la guvernare și al aliaților acestora. De asemenea, ar fi inclus mită către directorii Petrobras în schimbul unor contracte umflate. Recuperarea „miraculoasă” a unui elev supraviețuitor al masacrului de la Peshawar Un adolescent paralizat după ce fusese împușcat de patru ori în cel mai cumplit atac terorist din Pakistan a reușit o recuperare „miraculoasă” după ce a urmat un tratament în Regatul Unit. Lui Mohamed Ibrahim Khan, în vârstă de 13 ani, doctorii din Pakistan îi spuseseră că nu va mai putea să meargă niciodată.
+Cel puțin 140 de persoane, majoritatea copii, au fost ucise când bărbați înarmați au atacat școala publică a armatei din Peshawar în luna decembrie a anului trecut. Mohamed, care a sosit la Londra luna trecută pentru operație, va fi externat mai târziu din spital. Exact cu nouă luni în urmă, într-o dimineață obișnuită de marți, Mohamed stătea la ora de primul ajutor și își asculta atent profesorii. Chiar atunci, șapte bărbați înarmați deghizați în uniformele agenților de pază intrau în școala publică a armatei. Purtau centuri cu explozivi și aveau de îndeplinit o misiune simplă: să îi ucidă pe toți bărbații, femeile și copiii care le ieșeau în cale. „Nu pot uita ce s-a întâmplat în acea zi”, spune Mohamed cu o privire aspră.
+Stăteam în amfiteatru, puneam întrebări... apoi am auzit focuri de armă afară. Teroriștii au intrat înăuntru și au început să ucidă. Profesorul nostru a fost ars de viu. Mohamed descrie cum a scos patru elevi din amfiteatru în timp ce se desfășura carnagiul. Apoi spune că și-a auzit prietenul, pe Hamza, strigându-l. Spunea „oh, frate, salvează-mă”. L-am ținut de mână. Atunci eu am fost împușcat în spate, iar el în cap. Cei mai mulți dintre cei uciși în atac erau elevi Hamza a murit în brațele lui Mohamed. Mohamed își amintește că imediat după asta a leșinat și că următorul lucru pe care l-a știut a fost că se afla pe un pat de spital, paralizat de la brâu în jos.
+Doctorii din Peshawar din nordul Pakistanului, apoi cei din Rawalpindi, aproape de capitală, i-au spus familiei sale că nu exista tratament și că nu va mai putea merge niciodată. „Când l-am văzut, am simțit cum îmi iese sufletul”, spune Sher Khan, tatăl lui Mohamed. Acele nouă luni au fost cele mai grele din viața mea. Însă Khan și soția lui, Sherbano, au refuzat să creadă că fiul lor atât de pasionat de crichet nu-și va mai putea folosi vreodată picioarele. Au făcut o campanie și au cerut ajutor de la televiziunea pakistaneză, atrăgând sprijinul unor oameni faimoși precum Imran Khan, jucător de crichet devenit politician.
+Într-un final, au reușit să strângă fonduri pentru a-l duce pe Mohamed în Regatul Unit și a-i oferi tratament la clinica privată Harley Street din Londra. Neurochirurgul consultant Irfan Malik l-a descris pe Mohamed drept „înspăimântat” când acesta a ajuns la spital. „Își petrecuse ultimele [câteva] luni zăcând în pat, fără să se poată mișca de pe o parte pe alta, spune Malik. Era slăbit, se pusese multă presiune pe spatele lui. Nu era într-o formă prea bună. O vertebră de la baza coloanei vertebrale a lui Mohamed fusese distrusă Mohamed fusese împușcat în umăr, în șold și în spate în timpul atacului, iar coloana vertebrală inferioară îi fusese distrusă, ducând la paralizie.
+Însă, în timpul unei operații care a durat șase ore, Malik și echipa lui au reușit să lege din nou terminațiile nervoase și să reconstruiască partea distrusă a coloanei. Chiar și Malik a fost surprins de ceea ce s-a întâmplat în continuare. Exact la o săptămână după operație, Mohamed s-a ridicat și a început să facă pași și să meargă. Nu ne așteptam la un rezultat atât de bun. A fost un miracol”, spune acesta. În mai puțin de două săptămâni de la operație, Mohamed este gata să părăsească spitalul și să înceapă procesul lung de recuperare. Mohamed a sfidat soarta și a început să meargă din nou Vrea să devină puternic și să își continue studiile în Regatul Unit. Însă este hotărât să revină în Pakistan, să se înroleze în armată și să lupte împotriva terorismului.
+„Simt că am încă o șansă la viață” spune el, arătând imaginile cu arme desenate de el lângă manuale școlare și stilouri Fizic, Mohamed devine tot mai puternic în fiecare zi, însă trauma psihologică prin care trece și acum este de neimaginat. „Furia mea nu a scăzut”, mărturisește el. În școala mea au fost uciși copii mici. Ce crimă au comis ei? Mama lui își șterge o lacrimă, îl mângâie pe creștet și spune: „Îmi văd fiul mergând din nou”. Va putea să-și continue firesc viața. Serviciul 4G „Super Voice” de la Three oferă semnal mai bun Three folosește un spectru 4G cu o frecvență mai joasă, care poate acoperi o zonă mai extinsă
+Furnizorul de telefonie mobilă Three a lansat în Regatul Unit un serviciu despre care spune că va îmbunătăți recepția în interiorul clădirilor și în zonele rurale fără semnal. Serviciul 4G Super Voice le permite clienților să efectueze apeluri și să trimită mesaje text folosind un spectru cu o frecvență mai joasă. Și alte rețele intenționează să introducă aceeași tehnologie, cunoscută ca „Voice Over Long-Term Evolution (VoLTE)”. Aceasta funcționează momentan doar cu Samsung Galaxy S5, însă telefoanele iPhone recente vor beneficia de ea în lunile următoare. Three menționează că până la 5,5 milioane de clienți vor avea acces la serviciu până în 2017.
+Responsabilul șef pentru tehnologie, Bryn Jones a declarat: „Până la sfârșitul anului, un milion dintre clienții noștri vor avea acces la o acoperire mai bună în interior și își vor putea folosi telefoanele în mai multe locuri ca până acum”. Vedetele se pregătesc pentru stagiunea de pantomimă Stagiunea de pantomimă este foarte importantă pentru teatrele din tot Regatul Unit, multe dintre ele pregătindu-se acum pentru stagiunea din acest an. Acum, la teatrul de Crăciun participă unele dintre numele cele mai mari din showbusiness. Matthew Kelly și Hayley Mills vor apărea în Cenușăreasa - primul în rolul uneia dintre surorile rele, iar a doua în rolul zânei. Aceștia dezvăluie secretele pantomimei lor la BBC Breakfast. Steven Wilson: „Dacă nu fac nimic, mă simt vinovat”
+Steven Wilson a fost desemnat recent drept marele câștigător al Progressive Music Awards Steven Wilson a fost numit de multe ori drept cel mai muncitor muzician din lumea rockului progresiv. Talentatul muzician a câștigat trei premii la Progressive Music Awards, care a avut loc luna aceasta la Londra, printre care și premiul pentru cel mai bun album al anului pentru Hand. În recenzia sa de cinci stele, The Guardian a numit albumul „o operă de artă inteligentă, expresivă și captivantă”. Încă din anii 1980, Wilson este motorul mai multor proiecte muzicale, cel mai cunoscut dintre acestea fiind trupa de rock Porcupine Tree. Acum, înainte de două spectacole cu casa închisă la Royal Albert Hall, Wilson lansează un dublu LP doar în format vinil, Transience, pentru a arăta latura „mai accesibilă” a activității sale solo.
+A povestit pentru BBC despre dragostea lui pentru viniluri și despre programul său încărcat și a explicat cum a ajuns actorul de comedie Matt Berry să îi deschidă spectacolele. Ce înseamnă vinil pentru tine? Am crescut chiar în perioada de sfârșit a erei vinilurilor și îmi amintesc că atunci abia așteptam apariția CD-ului, căci vinilul era atât de enervant. Cumpărai un disc, mergeai cu el acasă, avea o zgârietură și trebuia să îl aduci înapoi. Iubesc CD-urile, iar pentru anumite tipuri de muzică, de exemplu cea clasică, sunt mai bune decât vinilurile. Însă problema cu CD-urile și cu descărcările digitale este aceea că nu mai există nimic pe care să îl prețuiești cu adevărat. Să ai un vinil e ca și cum ai avea un tablou frumos agățat în sufragerie.
+E ceva ce poți ține în mână, în timp ce te lași absorbit de versuri și copleșit de actul artistic. Am crezut că e doar o chestie nostalgică, însă nu are cum să fie așa dacă unor puști prea tineri să-și amintească de viniluri le place acest gen de experiență. Ai vreun vinil la care ții în mod special? Recunosc că am scăpat de toate vinilurile în anii '90. Toate vinilurile pe care le am sunt cumpărate din nou. Am pornit de la ideea de a reface colecția pe care o aveam la 15 ani, însă am trecut de limita aceea. Primul disc pe care mi-am convins părinții să mi-l cumpere a fost Out of the Blue de la Electric Light Orchestra.
+Dacă aș mai fi avut încă exemplarul inițial, acesta ar fi avut valoare sentimentală, însă, din păcate, se află pe undeva printr-un magazin de caritate. Steven Wilson speră că albumul va fi o poartă către posibili fani noi De ce ți-ai lansat noua compilație Transience pe vinil? Aceasta a fost concepută inițial ca idee pentru Ziua magazinelor de discuri, însă am ratat ocazia. Casa mea de discuri sugerase să adun câteva dintre melodiile mele mai scurte și mai accesibile. Am ajuns să fiu ușor obsedat de ideea de a face ceva gen „introducere în muzica lui Steven Wilson” și am ținut neapărat ca proiectul să fie lansat doar pe vinil. Cine cumpără vinilul primește, de asemenea, și o variantă descărcată la rezoluție înaltă.
+Ești îngrijorat că albumul nu va arăta muzica ta în adevărata ei lumină?
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/train_distil_marian_enro.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/train_distil_marian_enro.sh
new file mode 100644
index 0000000000000000000000000000000000000000..5e86a6991c579edcc91cf8bfe75def0b52746293
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/train_distil_marian_enro.sh
@@ -0,0 +1,38 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+export WANDB_PROJECT=distil-marian
+export BS=64
+export GAS=1
+export m=sshleifer/student_marian_en_ro_6_3
+export MAX_LEN=128
+python finetune_trainer.py \
+ --tokenizer_name $m --model_name_or_path $m \
+ --data_dir $ENRO_DIR \
+ --output_dir marian_en_ro_6_3 --overwrite_output_dir \
+ --learning_rate=3e-4 \
+ --warmup_steps 500 --sortish_sampler \
+ --fp16 \
+ --gradient_accumulation_steps=$GAS \
+ --per_device_train_batch_size=$BS --per_device_eval_batch_size=$BS \
+ --freeze_encoder --freeze_embeds \
+ --num_train_epochs=6 \
+ --save_steps 3000 --eval_steps 3000 \
+ --max_source_length $MAX_LEN --max_target_length $MAX_LEN \
+ --val_max_target_length $MAX_TGT_LEN --test_max_target_length $MAX_TGT_LEN \
+ --do_train --do_eval --do_predict \
+ --eval_strategy steps \
+ --predict_with_generate --logging_first_step \
+ --task translation --label_smoothing_factor 0.1 \
+ "$@"
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/train_distil_marian_enro_tpu.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/train_distil_marian_enro_tpu.sh
new file mode 100644
index 0000000000000000000000000000000000000000..00ef672261963bec60a8b1e4b9bdf5e1c55ce713
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/train_distil_marian_enro_tpu.sh
@@ -0,0 +1,39 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+export WANDB_PROJECT=distil-marian
+export BS=64
+export m=sshleifer/student_marian_en_ro_6_3
+export MAX_LEN=128
+export TPU_NUM_CORES=8
+
+python xla_spawn.py --num_cores $TPU_NUM_CORES \
+ finetune_trainer.py \
+ --tokenizer_name $m --model_name_or_path $m \
+ --data_dir $ENRO_DIR \
+ --output_dir marian_en_ro_6_3 --overwrite_output_dir \
+ --learning_rate=3e-4 \
+ --warmup_steps 500 \
+ --per_device_train_batch_size=$BS --per_device_eval_batch_size=$BS \
+ --freeze_encoder --freeze_embeds \
+ --num_train_epochs=6 \
+ --save_steps 500 --eval_steps 500 \
+ --logging_first_step --logging_steps 200 \
+ --max_source_length $MAX_LEN --max_target_length $MAX_LEN \
+ --val_max_target_length $MAX_TGT_LEN --test_max_target_length $MAX_TGT_LEN \
+ --do_train --do_eval \
+ --eval_strategy steps \
+ --prediction_loss_only \
+ --task translation --label_smoothing_factor 0.1 \
+ "$@"
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/train_distilbart_cnn.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/train_distilbart_cnn.sh
new file mode 100644
index 0000000000000000000000000000000000000000..42f34e0cb6e75a7fa313a951f1e725772716821b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/train_distilbart_cnn.sh
@@ -0,0 +1,39 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+export WANDB_PROJECT=distilbart-trainer
+export BS=32
+export m=sshleifer/student_cnn_12_6
+export tok=facebook/bart-large
+export MAX_TGT_LEN=142
+
+python finetune_trainer.py \
+ --model_name_or_path $m --tokenizer_name $tok \
+ --data_dir cnn_dm \
+ --output_dir distilbart-cnn-12-6 --overwrite_output_dir \
+ --learning_rate=3e-5 \
+ --warmup_steps 500 --sortish_sampler \
+ --fp16 \
+ --n_val 500 \
+ --gradient_accumulation_steps=1 \
+ --per_device_train_batch_size=$BS --per_device_eval_batch_size=$BS \
+ --freeze_encoder --freeze_embeds \
+ --num_train_epochs=2 \
+ --save_steps 3000 --eval_steps 3000 \
+ --logging_first_step \
+ --max_target_length 56 --val_max_target_length $MAX_TGT_LEN --test_max_target_length $MAX_TGT_LEN\
+ --do_train --do_eval --do_predict \
+ --eval_strategy steps \
+ --predict_with_generate --sortish_sampler \
+ "$@"
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/train_mbart_cc25_enro.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/train_mbart_cc25_enro.sh
new file mode 100644
index 0000000000000000000000000000000000000000..63c8051b47def1c80743e7cb38b948b33d20615d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/train_mbart_cc25_enro.sh
@@ -0,0 +1,35 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+python finetune_trainer.py \
+ --model_name_or_path=facebook/mbart-large-cc25 \
+ --data_dir $ENRO_DIR \
+ --output_dir mbart_cc25_enro --overwrite_output_dir \
+ --learning_rate=3e-5 \
+ --warmup_steps 500 \
+ --fp16 \
+ --label_smoothing 0.1 \
+ --adam_eps 1e-06 \
+ --src_lang en_XX --tgt_lang ro_RO \
+ --freeze_embeds \
+ --per_device_train_batch_size=4 --per_device_eval_batch_size=4 \
+ --max_source_length 128 --max_target_length 128 --val_max_target_length 128 --test_max_target_length 128\
+ --sortish_sampler \
+ --num_train_epochs 6 \
+ --save_steps 25000 --eval_steps 25000 --logging_steps 1000 \
+ --do_train --do_eval --do_predict \
+ --eval_strategy steps \
+ --predict_with_generate --logging_first_step \
+ --task translation \
+ "$@"
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/utils.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..d7cd84dedb287d54249f2b030fa3da06322b1aab
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/utils.py
@@ -0,0 +1,664 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import itertools
+import json
+import linecache
+import math
+import os
+import pickle
+import socket
+from logging import getLogger
+from pathlib import Path
+from typing import Callable, Dict, Iterable, List, Tuple, Union
+
+import git
+import numpy as np
+import torch
+import torch.distributed as dist
+from rouge_score import rouge_scorer, scoring
+from sacrebleu import corpus_bleu
+from sentence_splitter import add_newline_to_end_of_each_sentence
+from torch import nn
+from torch.utils.data import Dataset, Sampler
+
+from transformers import BartTokenizer, EvalPrediction, PreTrainedTokenizer, T5Tokenizer
+from transformers.models.bart.modeling_bart import shift_tokens_right
+from transformers.utils import cached_property
+
+
+try:
+ from fairseq.data.data_utils import batch_by_size
+
+ FAIRSEQ_AVAILABLE = True
+except (ImportError, ModuleNotFoundError):
+ FAIRSEQ_AVAILABLE = False
+
+
+def label_smoothed_nll_loss(lprobs, target, epsilon, ignore_index=-100):
+ """From fairseq"""
+ if target.dim() == lprobs.dim() - 1:
+ target = target.unsqueeze(-1)
+ nll_loss = -lprobs.gather(dim=-1, index=target)
+ smooth_loss = -lprobs.sum(dim=-1, keepdim=True)
+ if ignore_index is not None:
+ pad_mask = target.eq(ignore_index)
+ nll_loss.masked_fill_(pad_mask, 0.0)
+ smooth_loss.masked_fill_(pad_mask, 0.0)
+ else:
+ nll_loss = nll_loss.squeeze(-1)
+ smooth_loss = smooth_loss.squeeze(-1)
+
+ nll_loss = nll_loss.sum() # mean()? Scared to break other math.
+ smooth_loss = smooth_loss.sum()
+ eps_i = epsilon / lprobs.size(-1)
+ loss = (1.0 - epsilon) * nll_loss + eps_i * smooth_loss
+ return loss, nll_loss
+
+
+def lmap(f: Callable, x: Iterable) -> List:
+ """list(map(f, x))"""
+ return list(map(f, x))
+
+
+def calculate_bleu(output_lns, refs_lns, **kwargs) -> dict:
+ """Uses sacrebleu's corpus_bleu implementation."""
+ return {"bleu": round(corpus_bleu(output_lns, [refs_lns], **kwargs).score, 4)}
+
+
+def build_compute_metrics_fn(task_name: str, tokenizer: PreTrainedTokenizer) -> Callable[[EvalPrediction], Dict]:
+ def non_pad_len(tokens: np.ndarray) -> int:
+ return np.count_nonzero(tokens != tokenizer.pad_token_id)
+
+ def decode_pred(pred: EvalPrediction) -> Tuple[List[str], List[str]]:
+ pred_ids = pred.predictions
+ label_ids = pred.label_ids
+ pred_str = tokenizer.batch_decode(pred_ids, skip_special_tokens=True)
+ label_ids[label_ids == -100] = tokenizer.pad_token_id
+ label_str = tokenizer.batch_decode(label_ids, skip_special_tokens=True)
+ pred_str = lmap(str.strip, pred_str)
+ label_str = lmap(str.strip, label_str)
+ return pred_str, label_str
+
+ def summarization_metrics(pred: EvalPrediction) -> Dict:
+ pred_str, label_str = decode_pred(pred)
+ rouge: Dict = calculate_rouge(pred_str, label_str)
+ summ_len = np.round(np.mean(lmap(non_pad_len, pred.predictions)), 1)
+ rouge.update({"gen_len": summ_len})
+ return rouge
+
+ def translation_metrics(pred: EvalPrediction) -> Dict:
+ pred_str, label_str = decode_pred(pred)
+ bleu: Dict = calculate_bleu(pred_str, label_str)
+ gen_len = np.round(np.mean(lmap(non_pad_len, pred.predictions)), 1)
+ bleu.update({"gen_len": gen_len})
+ return bleu
+
+ compute_metrics_fn = summarization_metrics if "summarization" in task_name else translation_metrics
+ return compute_metrics_fn
+
+
+def trim_batch(
+ input_ids,
+ pad_token_id,
+ attention_mask=None,
+):
+ """Remove columns that are populated exclusively by pad_token_id"""
+ keep_column_mask = input_ids.ne(pad_token_id).any(dim=0)
+ if attention_mask is None:
+ return input_ids[:, keep_column_mask]
+ else:
+ return (input_ids[:, keep_column_mask], attention_mask[:, keep_column_mask])
+
+
+class AbstractSeq2SeqDataset(Dataset):
+ def __init__(
+ self,
+ tokenizer,
+ data_dir,
+ max_source_length,
+ max_target_length,
+ type_path="train",
+ n_obs=None,
+ prefix="",
+ **dataset_kwargs,
+ ):
+ super().__init__()
+ self.src_file = Path(data_dir).joinpath(type_path + ".source")
+ self.tgt_file = Path(data_dir).joinpath(type_path + ".target")
+ self.len_file = Path(data_dir).joinpath(type_path + ".len")
+ if os.path.exists(self.len_file):
+ self.src_lens = pickle_load(self.len_file)
+ self.used_char_len = False
+ else:
+ self.src_lens = self.get_char_lens(self.src_file)
+ self.used_char_len = True
+ self.max_source_length = max_source_length
+ self.max_target_length = max_target_length
+ assert min(self.src_lens) > 0, f"found empty line in {self.src_file}"
+ self.tokenizer = tokenizer
+ self.prefix = prefix if prefix is not None else ""
+
+ if n_obs is not None:
+ self.src_lens = self.src_lens[:n_obs]
+ self.pad_token_id = self.tokenizer.pad_token_id
+ self.dataset_kwargs = dataset_kwargs
+ dataset_kwargs.update({"add_prefix_space": True} if isinstance(self.tokenizer, BartTokenizer) else {})
+
+ def __len__(self):
+ return len(self.src_lens)
+
+ @staticmethod
+ def get_char_lens(data_file):
+ return [len(x) for x in Path(data_file).open().readlines()]
+
+ @cached_property
+ def tgt_lens(self):
+ """Length in characters of target documents"""
+ return self.get_char_lens(self.tgt_file)
+
+ def make_sortish_sampler(self, batch_size, distributed=False, shuffle=True, **kwargs):
+ if distributed:
+ return DistributedSortishSampler(self, batch_size, shuffle=shuffle, **kwargs)
+ else:
+ return SortishSampler(self.src_lens, batch_size, shuffle=shuffle)
+
+ def make_dynamic_sampler(self, max_tokens_per_batch=1024, **kwargs):
+ assert FAIRSEQ_AVAILABLE, "Dynamic batch size requires `pip install fairseq`"
+ assert not self.used_char_len, "You must call python make_len_file.py before calling make_dynamic_sampler"
+ sorted_indices = list(self.make_sortish_sampler(1024, shuffle=False))
+
+ def num_tokens_in_example(i):
+ return min(self.src_lens[i], self.max_target_length)
+
+ # call fairseq cython function
+ batch_sampler: List[List[int]] = batch_by_size(
+ sorted_indices,
+ num_tokens_fn=num_tokens_in_example,
+ max_tokens=max_tokens_per_batch,
+ required_batch_size_multiple=64,
+ )
+ shuffled_batches = [batch_sampler[i] for i in np.random.permutation(range(len(batch_sampler)))]
+ # move the largest batch to the front to OOM quickly (uses an approximation for padding)
+ approximate_toks_per_batch = [max(self.src_lens[i] for i in batch) * len(batch) for batch in shuffled_batches]
+ largest_batch_idx = np.argmax(approximate_toks_per_batch)
+ shuffled_batches[0], shuffled_batches[largest_batch_idx] = (
+ shuffled_batches[largest_batch_idx],
+ shuffled_batches[0],
+ )
+ return shuffled_batches
+
+ def __getitem__(self, item):
+ raise NotImplementedError("You must implement this")
+
+ def collate_fn(self, batch):
+ raise NotImplementedError("You must implement this")
+
+
+class LegacySeq2SeqDataset(AbstractSeq2SeqDataset):
+ def __getitem__(self, index) -> Dict[str, torch.Tensor]:
+ """Call tokenizer on src and tgt_lines"""
+ index = index + 1 # linecache starts at 1
+ source_line = self.prefix + linecache.getline(str(self.src_file), index).rstrip("\n")
+ tgt_line = linecache.getline(str(self.tgt_file), index).rstrip("\n")
+ assert source_line, f"empty source line for index {index}"
+ assert tgt_line, f"empty tgt line for index {index}"
+ source_inputs = self.encode_line(self.tokenizer, source_line, self.max_source_length)
+ target_inputs = self.encode_line(self.tokenizer, tgt_line, self.max_target_length)
+
+ source_ids = source_inputs["input_ids"].squeeze()
+ target_ids = target_inputs["input_ids"].squeeze()
+ src_mask = source_inputs["attention_mask"].squeeze()
+ return {
+ "input_ids": source_ids,
+ "attention_mask": src_mask,
+ "labels": target_ids,
+ }
+
+ def encode_line(self, tokenizer, line, max_length, pad_to_max_length=True, return_tensors="pt"):
+ """Only used by LegacyDataset"""
+ return tokenizer(
+ [line],
+ max_length=max_length,
+ padding="max_length" if pad_to_max_length else None,
+ truncation=True,
+ return_tensors=return_tensors,
+ **self.dataset_kwargs,
+ )
+
+ def collate_fn(self, batch) -> Dict[str, torch.Tensor]:
+ input_ids = torch.stack([x["input_ids"] for x in batch])
+ masks = torch.stack([x["attention_mask"] for x in batch])
+ target_ids = torch.stack([x["labels"] for x in batch])
+ pad_token_id = self.pad_token_id
+ y = trim_batch(target_ids, pad_token_id)
+ source_ids, source_mask = trim_batch(input_ids, pad_token_id, attention_mask=masks)
+ batch = {
+ "input_ids": source_ids,
+ "attention_mask": source_mask,
+ "labels": y,
+ }
+ return batch
+
+
+class Seq2SeqDataset(AbstractSeq2SeqDataset):
+ """A dataset that calls prepare_seq2seq_batch."""
+
+ def __getitem__(self, index) -> Dict[str, str]:
+ index = index + 1 # linecache starts at 1
+ source_line = self.prefix + linecache.getline(str(self.src_file), index).rstrip("\n")
+ tgt_line = linecache.getline(str(self.tgt_file), index).rstrip("\n")
+ assert source_line, f"empty source line for index {index}"
+ assert tgt_line, f"empty tgt line for index {index}"
+ return {"tgt_texts": tgt_line, "src_texts": source_line, "id": index - 1}
+
+ def collate_fn(self, batch) -> Dict[str, torch.Tensor]:
+ """Call prepare_seq2seq_batch."""
+ batch_encoding: Dict[str, torch.Tensor] = self.tokenizer.prepare_seq2seq_batch(
+ [x["src_texts"] for x in batch],
+ tgt_texts=[x["tgt_texts"] for x in batch],
+ max_length=self.max_source_length,
+ max_target_length=self.max_target_length,
+ return_tensors="pt",
+ **self.dataset_kwargs,
+ ).data
+ batch_encoding["ids"] = torch.tensor([x["id"] for x in batch])
+ return batch_encoding
+
+
+class Seq2SeqDataCollator:
+ def __init__(self, tokenizer, data_args, decoder_start_token_id, tpu_num_cores=None):
+ self.tokenizer = tokenizer
+ self.pad_token_id = tokenizer.pad_token_id
+ self.decoder_start_token_id = decoder_start_token_id
+ assert (
+ self.pad_token_id is not None
+ ), f"pad_token_id is not defined for ({self.tokenizer.__class__.__name__}), it must be defined."
+ self.data_args = data_args
+ self.tpu_num_cores = tpu_num_cores
+ self.dataset_kwargs = {"add_prefix_space": True} if isinstance(tokenizer, BartTokenizer) else {}
+ if data_args.src_lang is not None:
+ self.dataset_kwargs["src_lang"] = data_args.src_lang
+ if data_args.tgt_lang is not None:
+ self.dataset_kwargs["tgt_lang"] = data_args.tgt_lang
+
+ def __call__(self, batch) -> Dict[str, torch.Tensor]:
+ if hasattr(self.tokenizer, "prepare_seq2seq_batch"):
+ batch = self._encode(batch)
+ input_ids, attention_mask, labels = (
+ batch["input_ids"],
+ batch["attention_mask"],
+ batch["labels"],
+ )
+ else:
+ input_ids = torch.stack([x["input_ids"] for x in batch])
+ attention_mask = torch.stack([x["attention_mask"] for x in batch])
+ labels = torch.stack([x["labels"] for x in batch])
+
+ labels = trim_batch(labels, self.pad_token_id)
+ input_ids, attention_mask = trim_batch(input_ids, self.pad_token_id, attention_mask=attention_mask)
+
+ if isinstance(self.tokenizer, T5Tokenizer):
+ decoder_input_ids = self._shift_right_t5(labels)
+ else:
+ decoder_input_ids = shift_tokens_right(labels, self.pad_token_id, self.decoder_start_token_id)
+
+ batch = {
+ "input_ids": input_ids,
+ "attention_mask": attention_mask,
+ "decoder_input_ids": decoder_input_ids,
+ "labels": labels,
+ }
+ return batch
+
+ def _shift_right_t5(self, input_ids):
+ # shift inputs to the right
+ shifted_input_ids = input_ids.new_zeros(input_ids.shape)
+ shifted_input_ids[..., 1:] = input_ids[..., :-1].clone()
+ shifted_input_ids[..., 0] = self.pad_token_id
+ return shifted_input_ids
+
+ def _encode(self, batch) -> Dict[str, torch.Tensor]:
+ batch_encoding = self.tokenizer.prepare_seq2seq_batch(
+ [x["src_texts"] for x in batch],
+ tgt_texts=[x["tgt_texts"] for x in batch],
+ max_length=self.data_args.max_source_length,
+ max_target_length=self.data_args.max_target_length,
+ padding="max_length" if self.tpu_num_cores is not None else "longest", # TPU hack
+ return_tensors="pt",
+ **self.dataset_kwargs,
+ )
+ return batch_encoding.data
+
+
+class SortishSampler(Sampler):
+ "Go through the text data by order of src length with a bit of randomness. From fastai repo."
+
+ def __init__(self, data, batch_size, shuffle=True):
+ self.data, self.bs, self.shuffle = data, batch_size, shuffle
+
+ def __len__(self) -> int:
+ return len(self.data)
+
+ def __iter__(self):
+ return iter(sortish_sampler_indices(self.data, self.bs, shuffle=self.shuffle))
+
+
+def sortish_sampler_indices(data: List, bs: int, shuffle=True) -> np.array:
+ "Go through the text data by order of src length with a bit of randomness. From fastai repo."
+ if not shuffle:
+ return np.argsort(np.array(data) * -1)
+
+ def key_fn(i):
+ return data[i]
+
+ idxs = np.random.permutation(len(data))
+ sz = bs * 50
+ ck_idx = [idxs[i : i + sz] for i in range(0, len(idxs), sz)]
+ sort_idx = np.concatenate([sorted(s, key=key_fn, reverse=True) for s in ck_idx])
+ sz = bs
+ ck_idx = [sort_idx[i : i + sz] for i in range(0, len(sort_idx), sz)]
+ max_ck = np.argmax([key_fn(ck[0]) for ck in ck_idx]) # find the chunk with the largest key,
+ ck_idx[0], ck_idx[max_ck] = ck_idx[max_ck], ck_idx[0] # then make sure it goes first.
+ sort_idx = np.concatenate(np.random.permutation(ck_idx[1:])) if len(ck_idx) > 1 else np.array([], dtype=int)
+ sort_idx = np.concatenate((ck_idx[0], sort_idx))
+ return sort_idx
+
+
+class DistributedSortishSampler(Sampler):
+ """Copied from torch DistributedSampler"""
+
+ def __init__(self, dataset, batch_size, num_replicas=None, rank=None, add_extra_examples=True, shuffle=True):
+ if num_replicas is None:
+ if not dist.is_available():
+ raise RuntimeError("Requires distributed package to be available")
+ num_replicas = dist.get_world_size()
+ if rank is None:
+ if not dist.is_available():
+ raise RuntimeError("Requires distributed package to be available")
+ rank = dist.get_rank()
+ self.dataset = dataset
+ self.num_replicas = num_replicas
+ self.rank = rank
+ self.epoch = 0
+ if add_extra_examples:
+ self.num_samples = int(math.ceil(len(self.dataset) * 1.0 / self.num_replicas))
+ self.total_size = self.num_samples * self.num_replicas
+ else:
+ self.total_size = len(dataset)
+ self.num_samples = len(self.available_indices)
+ self.batch_size = batch_size
+ self.add_extra_examples = add_extra_examples
+ self.shuffle = shuffle
+
+ def __iter__(self) -> Iterable:
+ g = torch.Generator()
+ g.manual_seed(self.epoch)
+
+ sortish_data = [self.dataset.src_lens[i] for i in self.available_indices]
+ sortish_indices = sortish_sampler_indices(sortish_data, self.batch_size, shuffle=self.shuffle)
+ indices = [self.available_indices[i] for i in sortish_indices]
+ assert len(indices) == self.num_samples
+ return iter(indices)
+
+ @cached_property
+ def available_indices(self) -> np.array:
+ indices = list(range(len(self.dataset)))
+ # add extra samples to make it evenly divisible
+ indices += indices[: (self.total_size - len(indices))]
+ assert len(indices) == self.total_size
+ # subsample
+ available_indices = indices[self.rank : self.total_size : self.num_replicas]
+ return available_indices
+
+ def __len__(self):
+ return self.num_samples
+
+ def set_epoch(self, epoch):
+ self.epoch = epoch
+
+
+logger = getLogger(__name__)
+
+
+def use_task_specific_params(model, task):
+ """Update config with summarization specific params."""
+ task_specific_params = model.config.task_specific_params
+
+ if task_specific_params is not None:
+ pars = task_specific_params.get(task, {})
+ logger.info(f"setting model.config to task specific params for {task}:\n {pars}")
+ logger.info("note: command line args may override some of these")
+ model.config.update(pars)
+
+
+def pickle_load(path):
+ """pickle.load(path)"""
+ with open(path, "rb") as f:
+ return pickle.load(f)
+
+
+def pickle_save(obj, path):
+ """pickle.dump(obj, path)"""
+ with open(path, "wb") as f:
+ return pickle.dump(obj, f)
+
+
+def flatten_list(summary_ids: List[List]):
+ return list(itertools.chain.from_iterable(summary_ids))
+
+
+def save_git_info(folder_path: str) -> None:
+ """Save git information to output_dir/git_log.json"""
+ repo_infos = get_git_info()
+ save_json(repo_infos, os.path.join(folder_path, "git_log.json"))
+
+
+def save_json(content, path, indent=4, **json_dump_kwargs):
+ with open(path, "w") as f:
+ json.dump(content, f, indent=indent, sort_keys=True, **json_dump_kwargs)
+
+
+def load_json(path):
+ with open(path) as f:
+ return json.load(f)
+
+
+def get_git_info():
+ try:
+ repo = git.Repo(search_parent_directories=True)
+ repo_infos = {
+ "repo_id": str(repo),
+ "repo_sha": str(repo.head.object.hexsha),
+ "repo_branch": str(repo.active_branch),
+ "hostname": str(socket.gethostname()),
+ }
+ return repo_infos
+ except TypeError:
+ return {
+ "repo_id": None,
+ "repo_sha": None,
+ "repo_branch": None,
+ "hostname": None,
+ }
+
+
+ROUGE_KEYS = ["rouge1", "rouge2", "rougeL", "rougeLsum"]
+
+
+def extract_rouge_mid_statistics(dct):
+ new_dict = {}
+ for k1, v1 in dct.items():
+ mid = v1.mid
+ new_dict[k1] = {stat: round(getattr(mid, stat), 4) for stat in ["precision", "recall", "fmeasure"]}
+ return new_dict
+
+
+def calculate_rouge(
+ pred_lns: List[str],
+ tgt_lns: List[str],
+ use_stemmer=True,
+ rouge_keys=ROUGE_KEYS,
+ return_precision_and_recall=False,
+ bootstrap_aggregation=True,
+ newline_sep=True,
+) -> Dict:
+ """Calculate rouge using rouge_scorer package.
+
+ Args:
+ pred_lns: list of summaries generated by model
+ tgt_lns: list of groundtruth summaries (e.g. contents of val.target)
+ use_stemmer: Bool indicating whether Porter stemmer should be used to
+ strip word suffixes to improve matching.
+ rouge_keys: which metrics to compute, defaults to rouge1, rouge2, rougeL, rougeLsum
+ return_precision_and_recall: (False) whether to also return precision and recall.
+ bootstrap_aggregation: whether to do the typical bootstrap resampling of scores. Defaults to True, if False
+ this function returns a collections.defaultdict[metric: list of values for each observation for each subscore]``
+ newline_sep:(default=True) whether to add newline between sentences. This is essential for calculation rougeL
+ on multi sentence summaries (CNN/DM dataset).
+
+ Returns:
+ Dict[score: value] if aggregate else defaultdict(list) keyed by rouge_keys
+
+ """
+ scorer = rouge_scorer.RougeScorer(rouge_keys, use_stemmer=use_stemmer)
+ aggregator = scoring.BootstrapAggregator()
+ for pred, tgt in zip(tgt_lns, pred_lns):
+ # rougeLsum expects "\n" separated sentences within a summary
+ if newline_sep:
+ pred = add_newline_to_end_of_each_sentence(pred)
+ tgt = add_newline_to_end_of_each_sentence(tgt)
+ scores = scorer.score(pred, tgt)
+ aggregator.add_scores(scores)
+
+ if bootstrap_aggregation:
+ result = aggregator.aggregate()
+ if return_precision_and_recall:
+ return extract_rouge_mid_statistics(result) # here we return dict
+ else:
+ return {k: round(v.mid.fmeasure * 100, 4) for k, v in result.items()}
+
+ else:
+ return aggregator._scores # here we return defaultdict(list)
+
+
+# Utilities for freezing parameters and checking whether they are frozen
+
+
+def freeze_params(model: nn.Module):
+ """Set requires_grad=False for each of model.parameters()"""
+ for par in model.parameters():
+ par.requires_grad = False
+
+
+def freeze_embeds(model):
+ """Freeze token embeddings and positional embeddings for bart, just token embeddings for t5."""
+ model_type = model.config.model_type
+
+ if model_type in ["t5", "mt5"]:
+ freeze_params(model.shared)
+ for d in [model.encoder, model.decoder]:
+ freeze_params(d.embed_tokens)
+ elif model_type == "fsmt":
+ for d in [model.model.encoder, model.model.decoder]:
+ freeze_params(d.embed_positions)
+ freeze_params(d.embed_tokens)
+ else:
+ freeze_params(model.model.shared)
+ for d in [model.model.encoder, model.model.decoder]:
+ freeze_params(d.embed_positions)
+ freeze_params(d.embed_tokens)
+
+
+def grad_status(model: nn.Module) -> Iterable:
+ return (par.requires_grad for par in model.parameters())
+
+
+def any_requires_grad(model: nn.Module) -> bool:
+ return any(grad_status(model))
+
+
+def assert_all_frozen(model):
+ model_grads: List[bool] = list(grad_status(model))
+ n_require_grad = sum(lmap(int, model_grads))
+ npars = len(model_grads)
+ assert not any(model_grads), f"{n_require_grad/npars:.1%} of {npars} weights require grad"
+
+
+def assert_not_all_frozen(model):
+ model_grads: List[bool] = list(grad_status(model))
+ npars = len(model_grads)
+ assert any(model_grads), f"none of {npars} weights require grad"
+
+
+def parse_numeric_n_bool_cl_kwargs(unparsed_args: List[str]) -> Dict[str, Union[int, float, bool]]:
+ """
+ Parse an argv list of unspecified command line args to a dict.
+ Assumes all values are either numeric or boolean in the form of true/false.
+ """
+ result = {}
+ assert len(unparsed_args) % 2 == 0, f"got odd number of unparsed args: {unparsed_args}"
+ num_pairs = len(unparsed_args) // 2
+ for pair_num in range(num_pairs):
+ i = 2 * pair_num
+ assert unparsed_args[i].startswith("--")
+ if unparsed_args[i + 1].lower() == "true":
+ value = True
+ elif unparsed_args[i + 1].lower() == "false":
+ value = False
+ else:
+ try:
+ value = int(unparsed_args[i + 1])
+ except ValueError:
+ value = float(unparsed_args[i + 1]) # this can raise another informative ValueError
+
+ result[unparsed_args[i][2:]] = value
+ return result
+
+
+def write_txt_file(ordered_tgt, path):
+ f = Path(path).open("w")
+ for ln in ordered_tgt:
+ f.write(ln + "\n")
+ f.flush()
+
+
+def chunks(lst, n):
+ """Yield successive n-sized chunks from lst."""
+ for i in range(0, len(lst), n):
+ yield lst[i : i + n]
+
+
+def check_output_dir(args, expected_items=0):
+ """
+ Checks whether to bail out if output_dir already exists and has more than expected_items in it
+
+ `args`: needs to have the following attributes of `args`:
+ - output_dir
+ - do_train
+ - overwrite_output_dir
+
+ `expected_items`: normally 0 (default) - i.e. empty dir, but in some cases a few files are expected (e.g. recovery from OOM)
+ """
+ if (
+ os.path.exists(args.output_dir)
+ and len(os.listdir(args.output_dir)) > expected_items
+ and args.do_train
+ and not args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({args.output_dir}) already exists and "
+ f"has {len(os.listdir(args.output_dir))} items in it (expected {expected_items} items). "
+ "Use --overwrite_output_dir to overcome."
+ )
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/xla_spawn.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/xla_spawn.py
new file mode 100644
index 0000000000000000000000000000000000000000..f9955acfa201a77b12ab4391c14190434e748bbb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/seq2seq/xla_spawn.py
@@ -0,0 +1,82 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+A simple launcher script for TPU training
+
+Inspired by https://github.com/pytorch/pytorch/blob/master/torch/distributed/launch.py
+
+::
+ >>> python xla_spawn.py --num_cores=NUM_CORES_YOU_HAVE
+ YOUR_TRAINING_SCRIPT.py (--arg1 --arg2 --arg3 and all other
+ arguments of your training script)
+
+"""
+
+import importlib
+import sys
+from argparse import REMAINDER, ArgumentParser
+from pathlib import Path
+
+import torch_xla.distributed.xla_multiprocessing as xmp
+
+
+def parse_args():
+ """
+ Helper function parsing the command line options
+ @retval ArgumentParser
+ """
+ parser = ArgumentParser(
+ description=(
+ "PyTorch TPU distributed training launch helper utility that will spawn up multiple distributed processes"
+ )
+ )
+
+ # Optional arguments for the launch helper
+ parser.add_argument("--num_cores", type=int, default=1, help="Number of TPU cores to use (1 or 8).")
+
+ # positional
+ parser.add_argument(
+ "training_script",
+ type=str,
+ help=(
+ "The full path to the single TPU training "
+ "program/script to be launched in parallel, "
+ "followed by all the arguments for the "
+ "training script"
+ ),
+ )
+
+ # rest from the training program
+ parser.add_argument("training_script_args", nargs=REMAINDER)
+
+ return parser.parse_args()
+
+
+def main():
+ args = parse_args()
+
+ # Import training_script as a module.
+ script_fpath = Path(args.training_script)
+ sys.path.append(str(script_fpath.parent.resolve()))
+ mod_name = script_fpath.stem
+ mod = importlib.import_module(mod_name)
+
+ # Patch sys.argv
+ sys.argv = [args.training_script] + args.training_script_args + ["--tpu_num_cores", str(args.num_cores)]
+
+ xmp.spawn(mod._mp_fn, args=(), nprocs=args.num_cores)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..fbf17f84d2d7eed9ad889e77c8b965f9d5115abd
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/README.md
@@ -0,0 +1,294 @@
+## Token classification
+
+Based on the scripts [`run_ner.py`](https://github.com/huggingface/transformers/blob/main/examples/legacy/token-classification/run_ner.py).
+
+The following examples are covered in this section:
+
+* NER on the GermEval 2014 (German NER) dataset
+* Emerging and Rare Entities task: WNUT’17 (English NER) dataset
+
+Details and results for the fine-tuning provided by @stefan-it.
+
+### GermEval 2014 (German NER) dataset
+
+#### Data (Download and pre-processing steps)
+
+Data can be obtained from the [GermEval 2014](https://sites.google.com/site/germeval2014ner/data) shared task page.
+
+Here are the commands for downloading and pre-processing train, dev and test datasets. The original data format has four (tab-separated) columns, in a pre-processing step only the two relevant columns (token and outer span NER annotation) are extracted:
+
+```bash
+curl -L 'https://drive.google.com/uc?export=download&id=1Jjhbal535VVz2ap4v4r_rN1UEHTdLK5P' \
+| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > train.txt.tmp
+curl -L 'https://drive.google.com/uc?export=download&id=1ZfRcQThdtAR5PPRjIDtrVP7BtXSCUBbm' \
+| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > dev.txt.tmp
+curl -L 'https://drive.google.com/uc?export=download&id=1u9mb7kNJHWQCWyweMDRMuTFoOHOfeBTH' \
+| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > test.txt.tmp
+```
+
+The GermEval 2014 dataset contains some strange "control character" tokens like `'\x96', '\u200e', '\x95', '\xad' or '\x80'`.
+One problem with these tokens is, that `BertTokenizer` returns an empty token for them, resulting in misaligned `InputExample`s.
+The `preprocess.py` script located in the `scripts` folder a) filters these tokens and b) splits longer sentences into smaller ones (once the max. subtoken length is reached).
+
+Let's define some variables that we need for further pre-processing steps and training the model:
+
+```bash
+export MAX_LENGTH=128
+export BERT_MODEL=google-bert/bert-base-multilingual-cased
+```
+
+Run the pre-processing script on training, dev and test datasets:
+
+```bash
+python3 scripts/preprocess.py train.txt.tmp $BERT_MODEL $MAX_LENGTH > train.txt
+python3 scripts/preprocess.py dev.txt.tmp $BERT_MODEL $MAX_LENGTH > dev.txt
+python3 scripts/preprocess.py test.txt.tmp $BERT_MODEL $MAX_LENGTH > test.txt
+```
+
+The GermEval 2014 dataset has much more labels than CoNLL-2002/2003 datasets, so an own set of labels must be used:
+
+```bash
+cat train.txt dev.txt test.txt | cut -d " " -f 2 | grep -v "^$"| sort | uniq > labels.txt
+```
+
+#### Prepare the run
+
+Additional environment variables must be set:
+
+```bash
+export OUTPUT_DIR=germeval-model
+export BATCH_SIZE=32
+export NUM_EPOCHS=3
+export SAVE_STEPS=750
+export SEED=1
+```
+
+#### Run the Pytorch version
+
+To start training, just run:
+
+```bash
+python3 run_ner.py --data_dir ./ \
+--labels ./labels.txt \
+--model_name_or_path $BERT_MODEL \
+--output_dir $OUTPUT_DIR \
+--max_seq_length $MAX_LENGTH \
+--num_train_epochs $NUM_EPOCHS \
+--per_device_train_batch_size $BATCH_SIZE \
+--save_steps $SAVE_STEPS \
+--seed $SEED \
+--do_train \
+--do_eval \
+--do_predict
+```
+
+If your GPU supports half-precision training, just add the `--fp16` flag. After training, the model will be both evaluated on development and test datasets.
+
+#### JSON-based configuration file
+
+Instead of passing all parameters via commandline arguments, the `run_ner.py` script also supports reading parameters from a json-based configuration file:
+
+```json
+{
+ "data_dir": ".",
+ "labels": "./labels.txt",
+ "model_name_or_path": "google-bert/bert-base-multilingual-cased",
+ "output_dir": "germeval-model",
+ "max_seq_length": 128,
+ "num_train_epochs": 3,
+ "per_device_train_batch_size": 32,
+ "save_steps": 750,
+ "seed": 1,
+ "do_train": true,
+ "do_eval": true,
+ "do_predict": true
+}
+```
+
+It must be saved with a `.json` extension and can be used by running `python3 run_ner.py config.json`.
+
+#### Evaluation
+
+Evaluation on development dataset outputs the following for our example:
+
+```bash
+10/04/2019 00:42:06 - INFO - __main__ - ***** Eval results *****
+10/04/2019 00:42:06 - INFO - __main__ - f1 = 0.8623348017621146
+10/04/2019 00:42:06 - INFO - __main__ - loss = 0.07183869666975543
+10/04/2019 00:42:06 - INFO - __main__ - precision = 0.8467916366258111
+10/04/2019 00:42:06 - INFO - __main__ - recall = 0.8784592370979806
+```
+
+On the test dataset the following results could be achieved:
+
+```bash
+10/04/2019 00:42:42 - INFO - __main__ - ***** Eval results *****
+10/04/2019 00:42:42 - INFO - __main__ - f1 = 0.8614389652384803
+10/04/2019 00:42:42 - INFO - __main__ - loss = 0.07064602487454782
+10/04/2019 00:42:42 - INFO - __main__ - precision = 0.8604651162790697
+10/04/2019 00:42:42 - INFO - __main__ - recall = 0.8624150210424085
+```
+
+#### Run the Tensorflow 2 version
+
+To start training, just run:
+
+```bash
+python3 run_tf_ner.py --data_dir ./ \
+--labels ./labels.txt \
+--model_name_or_path $BERT_MODEL \
+--output_dir $OUTPUT_DIR \
+--max_seq_length $MAX_LENGTH \
+--num_train_epochs $NUM_EPOCHS \
+--per_device_train_batch_size $BATCH_SIZE \
+--save_steps $SAVE_STEPS \
+--seed $SEED \
+--do_train \
+--do_eval \
+--do_predict
+```
+
+Such as the Pytorch version, if your GPU supports half-precision training, just add the `--fp16` flag. After training, the model will be both evaluated on development and test datasets.
+
+#### Evaluation
+
+Evaluation on development dataset outputs the following for our example:
+```bash
+ precision recall f1-score support
+
+ LOCderiv 0.7619 0.6154 0.6809 52
+ PERpart 0.8724 0.8997 0.8858 4057
+ OTHpart 0.9360 0.9466 0.9413 711
+ ORGpart 0.7015 0.6989 0.7002 269
+ LOCpart 0.7668 0.8488 0.8057 496
+ LOC 0.8745 0.9191 0.8963 235
+ ORGderiv 0.7723 0.8571 0.8125 91
+ OTHderiv 0.4800 0.6667 0.5581 18
+ OTH 0.5789 0.6875 0.6286 16
+ PERderiv 0.5385 0.3889 0.4516 18
+ PER 0.5000 0.5000 0.5000 2
+ ORG 0.0000 0.0000 0.0000 3
+
+micro avg 0.8574 0.8862 0.8715 5968
+macro avg 0.8575 0.8862 0.8713 5968
+```
+
+On the test dataset the following results could be achieved:
+```bash
+ precision recall f1-score support
+
+ PERpart 0.8847 0.8944 0.8896 9397
+ OTHpart 0.9376 0.9353 0.9365 1639
+ ORGpart 0.7307 0.7044 0.7173 697
+ LOC 0.9133 0.9394 0.9262 561
+ LOCpart 0.8058 0.8157 0.8107 1150
+ ORG 0.0000 0.0000 0.0000 8
+ OTHderiv 0.5882 0.4762 0.5263 42
+ PERderiv 0.6571 0.5227 0.5823 44
+ OTH 0.4906 0.6667 0.5652 39
+ ORGderiv 0.7016 0.7791 0.7383 172
+ LOCderiv 0.8256 0.6514 0.7282 109
+ PER 0.0000 0.0000 0.0000 11
+
+micro avg 0.8722 0.8774 0.8748 13869
+macro avg 0.8712 0.8774 0.8740 13869
+```
+
+### Emerging and Rare Entities task: WNUT’17 (English NER) dataset
+
+Description of the WNUT’17 task from the [shared task website](http://noisy-text.github.io/2017/index.html):
+
+> The WNUT’17 shared task focuses on identifying unusual, previously-unseen entities in the context of emerging discussions.
+> Named entities form the basis of many modern approaches to other tasks (like event clustering and summarization), but recall on
+> them is a real problem in noisy text - even among annotators. This drop tends to be due to novel entities and surface forms.
+
+Six labels are available in the dataset. An overview can be found on this [page](http://noisy-text.github.io/2017/files/).
+
+#### Data (Download and pre-processing steps)
+
+The dataset can be downloaded from the [official GitHub](https://github.com/leondz/emerging_entities_17) repository.
+
+The following commands show how to prepare the dataset for fine-tuning:
+
+```bash
+mkdir -p data_wnut_17
+
+curl -L 'https://github.com/leondz/emerging_entities_17/raw/master/wnut17train.conll' | tr '\t' ' ' > data_wnut_17/train.txt.tmp
+curl -L 'https://github.com/leondz/emerging_entities_17/raw/master/emerging.dev.conll' | tr '\t' ' ' > data_wnut_17/dev.txt.tmp
+curl -L 'https://raw.githubusercontent.com/leondz/emerging_entities_17/master/emerging.test.annotated' | tr '\t' ' ' > data_wnut_17/test.txt.tmp
+```
+
+Let's define some variables that we need for further pre-processing steps:
+
+```bash
+export MAX_LENGTH=128
+export BERT_MODEL=google-bert/bert-large-cased
+```
+
+Here we use the English BERT large model for fine-tuning.
+The `preprocess.py` scripts splits longer sentences into smaller ones (once the max. subtoken length is reached):
+
+```bash
+python3 scripts/preprocess.py data_wnut_17/train.txt.tmp $BERT_MODEL $MAX_LENGTH > data_wnut_17/train.txt
+python3 scripts/preprocess.py data_wnut_17/dev.txt.tmp $BERT_MODEL $MAX_LENGTH > data_wnut_17/dev.txt
+python3 scripts/preprocess.py data_wnut_17/test.txt.tmp $BERT_MODEL $MAX_LENGTH > data_wnut_17/test.txt
+```
+
+In the last pre-processing step, the `labels.txt` file needs to be generated. This file contains all available labels:
+
+```bash
+cat data_wnut_17/train.txt data_wnut_17/dev.txt data_wnut_17/test.txt | cut -d " " -f 2 | grep -v "^$"| sort | uniq > data_wnut_17/labels.txt
+```
+
+#### Run the Pytorch version
+
+Fine-tuning with the PyTorch version can be started using the `run_ner.py` script. In this example we use a JSON-based configuration file.
+
+This configuration file looks like:
+
+```json
+{
+ "data_dir": "./data_wnut_17",
+ "labels": "./data_wnut_17/labels.txt",
+ "model_name_or_path": "google-bert/bert-large-cased",
+ "output_dir": "wnut-17-model-1",
+ "max_seq_length": 128,
+ "num_train_epochs": 3,
+ "per_device_train_batch_size": 32,
+ "save_steps": 425,
+ "seed": 1,
+ "do_train": true,
+ "do_eval": true,
+ "do_predict": true,
+ "fp16": false
+}
+```
+
+If your GPU supports half-precision training, please set `fp16` to `true`.
+
+Save this JSON-based configuration under `wnut_17.json`. The fine-tuning can be started with `python3 run_ner_old.py wnut_17.json`.
+
+#### Evaluation
+
+Evaluation on development dataset outputs the following:
+
+```bash
+05/29/2020 23:33:44 - INFO - __main__ - ***** Eval results *****
+05/29/2020 23:33:44 - INFO - __main__ - eval_loss = 0.26505235286212275
+05/29/2020 23:33:44 - INFO - __main__ - eval_precision = 0.7008264462809918
+05/29/2020 23:33:44 - INFO - __main__ - eval_recall = 0.507177033492823
+05/29/2020 23:33:44 - INFO - __main__ - eval_f1 = 0.5884802220680084
+05/29/2020 23:33:44 - INFO - __main__ - epoch = 3.0
+```
+
+On the test dataset the following results could be achieved:
+
+```bash
+05/29/2020 23:33:44 - INFO - transformers.trainer - ***** Running Prediction *****
+05/29/2020 23:34:02 - INFO - __main__ - eval_loss = 0.30948806500973547
+05/29/2020 23:34:02 - INFO - __main__ - eval_precision = 0.5840108401084011
+05/29/2020 23:34:02 - INFO - __main__ - eval_recall = 0.3994439295644115
+05/29/2020 23:34:02 - INFO - __main__ - eval_f1 = 0.47440836543753434
+```
+
+WNUT’17 is a very difficult task. Current state-of-the-art results on this dataset can be found [here](https://nlpprogress.com/english/named_entity_recognition.html).
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/run.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/run.sh
new file mode 100644
index 0000000000000000000000000000000000000000..b5f1e5f83bc7ffa20756edbfff35b8282caef828
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/run.sh
@@ -0,0 +1,36 @@
+## The relevant files are currently on a shared Google
+## drive at https://drive.google.com/drive/folders/1kC0I2UGl2ltrluI9NqDjaQJGw5iliw_J
+## Monitor for changes and eventually migrate to use the `datasets` library
+curl -L 'https://drive.google.com/uc?export=download&id=1Jjhbal535VVz2ap4v4r_rN1UEHTdLK5P' \
+| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > train.txt.tmp
+curl -L 'https://drive.google.com/uc?export=download&id=1ZfRcQThdtAR5PPRjIDtrVP7BtXSCUBbm' \
+| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > dev.txt.tmp
+curl -L 'https://drive.google.com/uc?export=download&id=1u9mb7kNJHWQCWyweMDRMuTFoOHOfeBTH' \
+| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > test.txt.tmp
+
+export MAX_LENGTH=128
+export BERT_MODEL=bert-base-multilingual-cased
+python3 scripts/preprocess.py train.txt.tmp $BERT_MODEL $MAX_LENGTH > train.txt
+python3 scripts/preprocess.py dev.txt.tmp $BERT_MODEL $MAX_LENGTH > dev.txt
+python3 scripts/preprocess.py test.txt.tmp $BERT_MODEL $MAX_LENGTH > test.txt
+cat train.txt dev.txt test.txt | cut -d " " -f 2 | grep -v "^$"| sort | uniq > labels.txt
+export OUTPUT_DIR=germeval-model
+export BATCH_SIZE=32
+export NUM_EPOCHS=3
+export SAVE_STEPS=750
+export SEED=1
+
+python3 run_ner.py \
+--task_type NER \
+--data_dir . \
+--labels ./labels.txt \
+--model_name_or_path $BERT_MODEL \
+--output_dir $OUTPUT_DIR \
+--max_seq_length $MAX_LENGTH \
+--num_train_epochs $NUM_EPOCHS \
+--per_gpu_train_batch_size $BATCH_SIZE \
+--save_steps $SAVE_STEPS \
+--seed $SEED \
+--do_train \
+--do_eval \
+--do_predict
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/run_chunk.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/run_chunk.sh
new file mode 100644
index 0000000000000000000000000000000000000000..13341555b699a45f3c2aed59672d950291f54dd4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/run_chunk.sh
@@ -0,0 +1,37 @@
+if ! [ -f ./dev.txt ]; then
+ echo "Downloading CONLL2003 dev dataset...."
+ curl -L -o ./dev.txt 'https://github.com/davidsbatista/NER-datasets/raw/master/CONLL2003/valid.txt'
+fi
+
+if ! [ -f ./test.txt ]; then
+ echo "Downloading CONLL2003 test dataset...."
+ curl -L -o ./test.txt 'https://github.com/davidsbatista/NER-datasets/raw/master/CONLL2003/test.txt'
+fi
+
+if ! [ -f ./train.txt ]; then
+ echo "Downloading CONLL2003 train dataset...."
+ curl -L -o ./train.txt 'https://github.com/davidsbatista/NER-datasets/raw/master/CONLL2003/train.txt'
+fi
+
+export MAX_LENGTH=200
+export BERT_MODEL=bert-base-uncased
+export OUTPUT_DIR=chunker-model
+export BATCH_SIZE=32
+export NUM_EPOCHS=3
+export SAVE_STEPS=750
+export SEED=1
+
+python3 run_ner.py \
+--task_type Chunk \
+--data_dir . \
+--model_name_or_path $BERT_MODEL \
+--output_dir $OUTPUT_DIR \
+--max_seq_length $MAX_LENGTH \
+--num_train_epochs $NUM_EPOCHS \
+--per_gpu_train_batch_size $BATCH_SIZE \
+--save_steps $SAVE_STEPS \
+--seed $SEED \
+--do_train \
+--do_eval \
+--do_predict
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/run_ner.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/run_ner.py
new file mode 100644
index 0000000000000000000000000000000000000000..4fb74e78ff9fe169d66549e8f95200fbb91f80e3
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/run_ner.py
@@ -0,0 +1,325 @@
+# coding=utf-8
+# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fine-tuning the library models for named entity recognition on CoNLL-2003."""
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from importlib import import_module
+from typing import Dict, List, Optional, Tuple
+
+import numpy as np
+from seqeval.metrics import accuracy_score, f1_score, precision_score, recall_score
+from torch import nn
+from utils_ner import Split, TokenClassificationDataset, TokenClassificationTask
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForTokenClassification,
+ AutoTokenizer,
+ DataCollatorWithPadding,
+ EvalPrediction,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ set_seed,
+)
+from transformers.trainer_utils import is_main_process
+
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ task_type: Optional[str] = field(
+ default="NER", metadata={"help": "Task type to fine tune in training (e.g. NER, POS, etc)"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ use_fast: bool = field(default=False, metadata={"help": "Set this flag to use fast tokenization."})
+ # If you want to tweak more attributes on your tokenizer, you should do it in a distinct script,
+ # or just modify its tokenizer_config.json.
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ data_dir: str = field(
+ metadata={"help": "The input data dir. Should contain the .txt files for a CoNLL-2003-formatted task."}
+ )
+ labels: Optional[str] = field(
+ default=None,
+ metadata={"help": "Path to a file containing all labels. If not specified, CoNLL-2003 labels are used."},
+ )
+ max_seq_length: int = field(
+ default=128,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ if (
+ os.path.exists(training_args.output_dir)
+ and os.listdir(training_args.output_dir)
+ and training_args.do_train
+ and not training_args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. Use"
+ " --overwrite_output_dir to overcome."
+ )
+
+ module = import_module("tasks")
+ try:
+ token_classification_task_clazz = getattr(module, model_args.task_type)
+ token_classification_task: TokenClassificationTask = token_classification_task_clazz()
+ except AttributeError:
+ raise ValueError(
+ f"Task {model_args.task_type} needs to be defined as a TokenClassificationTask subclass in {module}. "
+ f"Available tasks classes are: {TokenClassificationTask.__subclasses__()}"
+ )
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO if training_args.local_rank in [-1, 0] else logging.WARN,
+ )
+ logger.warning(
+ "Process rank: %s, device: %s, n_gpu: %s, distributed training: %s, 16-bits training: %s",
+ training_args.local_rank,
+ training_args.device,
+ training_args.n_gpu,
+ bool(training_args.local_rank != -1),
+ training_args.fp16,
+ )
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ if is_main_process(training_args.local_rank):
+ transformers.utils.logging.set_verbosity_info()
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+ logger.info("Training/evaluation parameters %s", training_args)
+
+ # Set seed
+ set_seed(training_args.seed)
+
+ # Prepare CONLL-2003 task
+ labels = token_classification_task.get_labels(data_args.labels)
+ label_map: Dict[int, str] = dict(enumerate(labels))
+ num_labels = len(labels)
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ num_labels=num_labels,
+ id2label=label_map,
+ label2id={label: i for i, label in enumerate(labels)},
+ cache_dir=model_args.cache_dir,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast,
+ )
+ model = AutoModelForTokenClassification.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ )
+
+ # Get datasets
+ train_dataset = (
+ TokenClassificationDataset(
+ token_classification_task=token_classification_task,
+ data_dir=data_args.data_dir,
+ tokenizer=tokenizer,
+ labels=labels,
+ model_type=config.model_type,
+ max_seq_length=data_args.max_seq_length,
+ overwrite_cache=data_args.overwrite_cache,
+ mode=Split.train,
+ )
+ if training_args.do_train
+ else None
+ )
+ eval_dataset = (
+ TokenClassificationDataset(
+ token_classification_task=token_classification_task,
+ data_dir=data_args.data_dir,
+ tokenizer=tokenizer,
+ labels=labels,
+ model_type=config.model_type,
+ max_seq_length=data_args.max_seq_length,
+ overwrite_cache=data_args.overwrite_cache,
+ mode=Split.dev,
+ )
+ if training_args.do_eval
+ else None
+ )
+
+ def align_predictions(predictions: np.ndarray, label_ids: np.ndarray) -> Tuple[List[int], List[int]]:
+ preds = np.argmax(predictions, axis=2)
+
+ batch_size, seq_len = preds.shape
+
+ out_label_list = [[] for _ in range(batch_size)]
+ preds_list = [[] for _ in range(batch_size)]
+
+ for i in range(batch_size):
+ for j in range(seq_len):
+ if label_ids[i, j] != nn.CrossEntropyLoss().ignore_index:
+ out_label_list[i].append(label_map[label_ids[i][j]])
+ preds_list[i].append(label_map[preds[i][j]])
+
+ return preds_list, out_label_list
+
+ def compute_metrics(p: EvalPrediction) -> Dict:
+ preds_list, out_label_list = align_predictions(p.predictions, p.label_ids)
+ return {
+ "accuracy_score": accuracy_score(out_label_list, preds_list),
+ "precision": precision_score(out_label_list, preds_list),
+ "recall": recall_score(out_label_list, preds_list),
+ "f1": f1_score(out_label_list, preds_list),
+ }
+
+ # Data collator
+ data_collator = DataCollatorWithPadding(tokenizer, pad_to_multiple_of=8) if training_args.fp16 else None
+
+ # Initialize our Trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset,
+ eval_dataset=eval_dataset,
+ compute_metrics=compute_metrics,
+ data_collator=data_collator,
+ )
+
+ # Training
+ if training_args.do_train:
+ trainer.train(
+ model_path=model_args.model_name_or_path if os.path.isdir(model_args.model_name_or_path) else None
+ )
+ trainer.save_model()
+ # For convenience, we also re-save the tokenizer to the same directory,
+ # so that you can share your model easily on huggingface.co/models =)
+ if trainer.is_world_process_zero():
+ tokenizer.save_pretrained(training_args.output_dir)
+
+ # Evaluation
+ results = {}
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+
+ result = trainer.evaluate()
+
+ output_eval_file = os.path.join(training_args.output_dir, "eval_results.txt")
+ if trainer.is_world_process_zero():
+ with open(output_eval_file, "w") as writer:
+ logger.info("***** Eval results *****")
+ for key, value in result.items():
+ logger.info(" %s = %s", key, value)
+ writer.write("%s = %s\n" % (key, value))
+
+ results.update(result)
+
+ # Predict
+ if training_args.do_predict:
+ test_dataset = TokenClassificationDataset(
+ token_classification_task=token_classification_task,
+ data_dir=data_args.data_dir,
+ tokenizer=tokenizer,
+ labels=labels,
+ model_type=config.model_type,
+ max_seq_length=data_args.max_seq_length,
+ overwrite_cache=data_args.overwrite_cache,
+ mode=Split.test,
+ )
+
+ predictions, label_ids, metrics = trainer.predict(test_dataset)
+ preds_list, _ = align_predictions(predictions, label_ids)
+
+ output_test_results_file = os.path.join(training_args.output_dir, "test_results.txt")
+ if trainer.is_world_process_zero():
+ with open(output_test_results_file, "w") as writer:
+ for key, value in metrics.items():
+ logger.info(" %s = %s", key, value)
+ writer.write("%s = %s\n" % (key, value))
+
+ # Save predictions
+ output_test_predictions_file = os.path.join(training_args.output_dir, "test_predictions.txt")
+ if trainer.is_world_process_zero():
+ with open(output_test_predictions_file, "w") as writer:
+ with open(os.path.join(data_args.data_dir, "test.txt"), "r") as f:
+ token_classification_task.write_predictions_to_file(writer, f, preds_list)
+
+ return results
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/run_pos.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/run_pos.sh
new file mode 100644
index 0000000000000000000000000000000000000000..7d76ed8a2a8a94bc2cd258c42b78bcdb9ba3243b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/run_pos.sh
@@ -0,0 +1,37 @@
+if ! [ -f ./dev.txt ]; then
+ echo "Download dev dataset...."
+ curl -L -o ./dev.txt 'https://github.com/UniversalDependencies/UD_English-EWT/raw/master/en_ewt-ud-dev.conllu'
+fi
+
+if ! [ -f ./test.txt ]; then
+ echo "Download test dataset...."
+ curl -L -o ./test.txt 'https://github.com/UniversalDependencies/UD_English-EWT/raw/master/en_ewt-ud-test.conllu'
+fi
+
+if ! [ -f ./train.txt ]; then
+ echo "Download train dataset...."
+ curl -L -o ./train.txt 'https://github.com/UniversalDependencies/UD_English-EWT/raw/master/en_ewt-ud-train.conllu'
+fi
+
+export MAX_LENGTH=200
+export BERT_MODEL=bert-base-uncased
+export OUTPUT_DIR=postagger-model
+export BATCH_SIZE=32
+export NUM_EPOCHS=3
+export SAVE_STEPS=750
+export SEED=1
+
+python3 run_ner.py \
+--task_type POS \
+--data_dir . \
+--model_name_or_path $BERT_MODEL \
+--output_dir $OUTPUT_DIR \
+--max_seq_length $MAX_LENGTH \
+--num_train_epochs $NUM_EPOCHS \
+--per_gpu_train_batch_size $BATCH_SIZE \
+--save_steps $SAVE_STEPS \
+--seed $SEED \
+--do_train \
+--do_eval \
+--do_predict
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/scripts/preprocess.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/scripts/preprocess.py
new file mode 100644
index 0000000000000000000000000000000000000000..4eaa4fe2f3b79dda5a1dbaf66890d45524b91592
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/scripts/preprocess.py
@@ -0,0 +1,41 @@
+import sys
+
+from transformers import AutoTokenizer
+
+
+dataset = sys.argv[1]
+model_name_or_path = sys.argv[2]
+max_len = int(sys.argv[3])
+
+subword_len_counter = 0
+
+tokenizer = AutoTokenizer.from_pretrained(model_name_or_path)
+max_len -= tokenizer.num_special_tokens_to_add()
+
+with open(dataset, "rt") as f_p:
+ for line in f_p:
+ line = line.rstrip()
+
+ if not line:
+ print(line)
+ subword_len_counter = 0
+ continue
+
+ token = line.split()[0]
+
+ current_subwords_len = len(tokenizer.tokenize(token))
+
+ # Token contains strange control characters like \x96 or \x95
+ # Just filter out the complete line
+ if current_subwords_len == 0:
+ continue
+
+ if (subword_len_counter + current_subwords_len) > max_len:
+ print("")
+ print(line)
+ subword_len_counter = current_subwords_len
+ continue
+
+ subword_len_counter += current_subwords_len
+
+ print(line)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/tasks.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/tasks.py
new file mode 100644
index 0000000000000000000000000000000000000000..d893a2ab0347df8302063890fc046c78e59b8373
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/tasks.py
@@ -0,0 +1,162 @@
+import logging
+import os
+from typing import List, TextIO, Union
+
+from conllu import parse_incr
+from utils_ner import InputExample, Split, TokenClassificationTask
+
+
+logger = logging.getLogger(__name__)
+
+
+class NER(TokenClassificationTask):
+ def __init__(self, label_idx=-1):
+ # in NER datasets, the last column is usually reserved for NER label
+ self.label_idx = label_idx
+
+ def read_examples_from_file(self, data_dir, mode: Union[Split, str]) -> List[InputExample]:
+ if isinstance(mode, Split):
+ mode = mode.value
+ file_path = os.path.join(data_dir, f"{mode}.txt")
+ guid_index = 1
+ examples = []
+ with open(file_path, encoding="utf-8") as f:
+ words = []
+ labels = []
+ for line in f:
+ if line.startswith("-DOCSTART-") or line == "" or line == "\n":
+ if words:
+ examples.append(InputExample(guid=f"{mode}-{guid_index}", words=words, labels=labels))
+ guid_index += 1
+ words = []
+ labels = []
+ else:
+ splits = line.split(" ")
+ words.append(splits[0])
+ if len(splits) > 1:
+ labels.append(splits[self.label_idx].replace("\n", ""))
+ else:
+ # Examples could have no label for mode = "test"
+ labels.append("O")
+ if words:
+ examples.append(InputExample(guid=f"{mode}-{guid_index}", words=words, labels=labels))
+ return examples
+
+ def write_predictions_to_file(self, writer: TextIO, test_input_reader: TextIO, preds_list: List):
+ example_id = 0
+ for line in test_input_reader:
+ if line.startswith("-DOCSTART-") or line == "" or line == "\n":
+ writer.write(line)
+ if not preds_list[example_id]:
+ example_id += 1
+ elif preds_list[example_id]:
+ output_line = line.split()[0] + " " + preds_list[example_id].pop(0) + "\n"
+ writer.write(output_line)
+ else:
+ logger.warning("Maximum sequence length exceeded: No prediction for '%s'.", line.split()[0])
+
+ def get_labels(self, path: str) -> List[str]:
+ if path:
+ with open(path, "r") as f:
+ labels = f.read().splitlines()
+ if "O" not in labels:
+ labels = ["O"] + labels
+ return labels
+ else:
+ return ["O", "B-MISC", "I-MISC", "B-PER", "I-PER", "B-ORG", "I-ORG", "B-LOC", "I-LOC"]
+
+
+class Chunk(NER):
+ def __init__(self):
+ # in CONLL2003 dataset chunk column is second-to-last
+ super().__init__(label_idx=-2)
+
+ def get_labels(self, path: str) -> List[str]:
+ if path:
+ with open(path, "r") as f:
+ labels = f.read().splitlines()
+ if "O" not in labels:
+ labels = ["O"] + labels
+ return labels
+ else:
+ return [
+ "O",
+ "B-ADVP",
+ "B-INTJ",
+ "B-LST",
+ "B-PRT",
+ "B-NP",
+ "B-SBAR",
+ "B-VP",
+ "B-ADJP",
+ "B-CONJP",
+ "B-PP",
+ "I-ADVP",
+ "I-INTJ",
+ "I-LST",
+ "I-PRT",
+ "I-NP",
+ "I-SBAR",
+ "I-VP",
+ "I-ADJP",
+ "I-CONJP",
+ "I-PP",
+ ]
+
+
+class POS(TokenClassificationTask):
+ def read_examples_from_file(self, data_dir, mode: Union[Split, str]) -> List[InputExample]:
+ if isinstance(mode, Split):
+ mode = mode.value
+ file_path = os.path.join(data_dir, f"{mode}.txt")
+ guid_index = 1
+ examples = []
+
+ with open(file_path, encoding="utf-8") as f:
+ for sentence in parse_incr(f):
+ words = []
+ labels = []
+ for token in sentence:
+ words.append(token["form"])
+ labels.append(token["upos"])
+ assert len(words) == len(labels)
+ if words:
+ examples.append(InputExample(guid=f"{mode}-{guid_index}", words=words, labels=labels))
+ guid_index += 1
+ return examples
+
+ def write_predictions_to_file(self, writer: TextIO, test_input_reader: TextIO, preds_list: List):
+ example_id = 0
+ for sentence in parse_incr(test_input_reader):
+ s_p = preds_list[example_id]
+ out = ""
+ for token in sentence:
+ out += f'{token["form"]} ({token["upos"]}|{s_p.pop(0)}) '
+ out += "\n"
+ writer.write(out)
+ example_id += 1
+
+ def get_labels(self, path: str) -> List[str]:
+ if path:
+ with open(path, "r") as f:
+ return f.read().splitlines()
+ else:
+ return [
+ "ADJ",
+ "ADP",
+ "ADV",
+ "AUX",
+ "CCONJ",
+ "DET",
+ "INTJ",
+ "NOUN",
+ "NUM",
+ "PART",
+ "PRON",
+ "PROPN",
+ "PUNCT",
+ "SCONJ",
+ "SYM",
+ "VERB",
+ "X",
+ ]
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/utils_ner.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/utils_ner.py
new file mode 100644
index 0000000000000000000000000000000000000000..da4d8c3b6059fd62a44066bcd47a9ff0704591b2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/legacy/token-classification/utils_ner.py
@@ -0,0 +1,371 @@
+# coding=utf-8
+# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Named entity recognition fine-tuning: utilities to work with CoNLL-2003 task."""
+
+import logging
+import os
+from dataclasses import dataclass
+from enum import Enum
+from typing import List, Optional, Union
+
+from filelock import FileLock
+
+from transformers import PreTrainedTokenizer, is_tf_available, is_torch_available
+
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class InputExample:
+ """
+ A single training/test example for token classification.
+
+ Args:
+ guid: Unique id for the example.
+ words: list. The words of the sequence.
+ labels: (Optional) list. The labels for each word of the sequence. This should be
+ specified for train and dev examples, but not for test examples.
+ """
+
+ guid: str
+ words: List[str]
+ labels: Optional[List[str]]
+
+
+@dataclass
+class InputFeatures:
+ """
+ A single set of features of data.
+ Property names are the same names as the corresponding inputs to a model.
+ """
+
+ input_ids: List[int]
+ attention_mask: List[int]
+ token_type_ids: Optional[List[int]] = None
+ label_ids: Optional[List[int]] = None
+
+
+class Split(Enum):
+ train = "train"
+ dev = "dev"
+ test = "test"
+
+
+class TokenClassificationTask:
+ @staticmethod
+ def read_examples_from_file(data_dir, mode: Union[Split, str]) -> List[InputExample]:
+ raise NotImplementedError
+
+ @staticmethod
+ def get_labels(path: str) -> List[str]:
+ raise NotImplementedError
+
+ @staticmethod
+ def convert_examples_to_features(
+ examples: List[InputExample],
+ label_list: List[str],
+ max_seq_length: int,
+ tokenizer: PreTrainedTokenizer,
+ cls_token_at_end=False,
+ cls_token="[CLS]",
+ cls_token_segment_id=1,
+ sep_token="[SEP]",
+ sep_token_extra=False,
+ pad_on_left=False,
+ pad_token=0,
+ pad_token_segment_id=0,
+ pad_token_label_id=-100,
+ sequence_a_segment_id=0,
+ mask_padding_with_zero=True,
+ ) -> List[InputFeatures]:
+ """Loads a data file into a list of `InputFeatures`
+ `cls_token_at_end` define the location of the CLS token:
+ - False (Default, BERT/XLM pattern): [CLS] + A + [SEP] + B + [SEP]
+ - True (XLNet/GPT pattern): A + [SEP] + B + [SEP] + [CLS]
+ `cls_token_segment_id` define the segment id associated to the CLS token (0 for BERT, 2 for XLNet)
+ """
+ # TODO clean up all this to leverage built-in features of tokenizers
+
+ label_map = {label: i for i, label in enumerate(label_list)}
+
+ features = []
+ for ex_index, example in enumerate(examples):
+ if ex_index % 10_000 == 0:
+ logger.info("Writing example %d of %d", ex_index, len(examples))
+
+ tokens = []
+ label_ids = []
+ for word, label in zip(example.words, example.labels):
+ word_tokens = tokenizer.tokenize(word)
+
+ # google-bert/bert-base-multilingual-cased sometimes output "nothing ([]) when calling tokenize with just a space.
+ if len(word_tokens) > 0:
+ tokens.extend(word_tokens)
+ # Use the real label id for the first token of the word, and padding ids for the remaining tokens
+ label_ids.extend([label_map[label]] + [pad_token_label_id] * (len(word_tokens) - 1))
+
+ # Account for [CLS] and [SEP] with "- 2" and with "- 3" for RoBERTa.
+ special_tokens_count = tokenizer.num_special_tokens_to_add()
+ if len(tokens) > max_seq_length - special_tokens_count:
+ tokens = tokens[: (max_seq_length - special_tokens_count)]
+ label_ids = label_ids[: (max_seq_length - special_tokens_count)]
+
+ # The convention in BERT is:
+ # (a) For sequence pairs:
+ # tokens: [CLS] is this jack ##son ##ville ? [SEP] no it is not . [SEP]
+ # type_ids: 0 0 0 0 0 0 0 0 1 1 1 1 1 1
+ # (b) For single sequences:
+ # tokens: [CLS] the dog is hairy . [SEP]
+ # type_ids: 0 0 0 0 0 0 0
+ #
+ # Where "type_ids" are used to indicate whether this is the first
+ # sequence or the second sequence. The embedding vectors for `type=0` and
+ # `type=1` were learned during pre-training and are added to the wordpiece
+ # embedding vector (and position vector). This is not *strictly* necessary
+ # since the [SEP] token unambiguously separates the sequences, but it makes
+ # it easier for the model to learn the concept of sequences.
+ #
+ # For classification tasks, the first vector (corresponding to [CLS]) is
+ # used as the "sentence vector". Note that this only makes sense because
+ # the entire model is fine-tuned.
+ tokens += [sep_token]
+ label_ids += [pad_token_label_id]
+ if sep_token_extra:
+ # roberta uses an extra separator b/w pairs of sentences
+ tokens += [sep_token]
+ label_ids += [pad_token_label_id]
+ segment_ids = [sequence_a_segment_id] * len(tokens)
+
+ if cls_token_at_end:
+ tokens += [cls_token]
+ label_ids += [pad_token_label_id]
+ segment_ids += [cls_token_segment_id]
+ else:
+ tokens = [cls_token] + tokens
+ label_ids = [pad_token_label_id] + label_ids
+ segment_ids = [cls_token_segment_id] + segment_ids
+
+ input_ids = tokenizer.convert_tokens_to_ids(tokens)
+
+ # The mask has 1 for real tokens and 0 for padding tokens. Only real
+ # tokens are attended to.
+ input_mask = [1 if mask_padding_with_zero else 0] * len(input_ids)
+
+ # Zero-pad up to the sequence length.
+ padding_length = max_seq_length - len(input_ids)
+ if pad_on_left:
+ input_ids = ([pad_token] * padding_length) + input_ids
+ input_mask = ([0 if mask_padding_with_zero else 1] * padding_length) + input_mask
+ segment_ids = ([pad_token_segment_id] * padding_length) + segment_ids
+ label_ids = ([pad_token_label_id] * padding_length) + label_ids
+ else:
+ input_ids += [pad_token] * padding_length
+ input_mask += [0 if mask_padding_with_zero else 1] * padding_length
+ segment_ids += [pad_token_segment_id] * padding_length
+ label_ids += [pad_token_label_id] * padding_length
+
+ assert len(input_ids) == max_seq_length
+ assert len(input_mask) == max_seq_length
+ assert len(segment_ids) == max_seq_length
+ assert len(label_ids) == max_seq_length
+
+ if ex_index < 5:
+ logger.info("*** Example ***")
+ logger.info("guid: %s", example.guid)
+ logger.info("tokens: %s", " ".join([str(x) for x in tokens]))
+ logger.info("input_ids: %s", " ".join([str(x) for x in input_ids]))
+ logger.info("input_mask: %s", " ".join([str(x) for x in input_mask]))
+ logger.info("segment_ids: %s", " ".join([str(x) for x in segment_ids]))
+ logger.info("label_ids: %s", " ".join([str(x) for x in label_ids]))
+
+ if "token_type_ids" not in tokenizer.model_input_names:
+ segment_ids = None
+
+ features.append(
+ InputFeatures(
+ input_ids=input_ids, attention_mask=input_mask, token_type_ids=segment_ids, label_ids=label_ids
+ )
+ )
+ return features
+
+
+if is_torch_available():
+ import torch
+ from torch import nn
+ from torch.utils.data import Dataset
+
+ class TokenClassificationDataset(Dataset):
+ """
+ This will be superseded by a framework-agnostic approach
+ soon.
+ """
+
+ features: List[InputFeatures]
+ pad_token_label_id: int = nn.CrossEntropyLoss().ignore_index
+ # Use cross entropy ignore_index as padding label id so that only
+ # real label ids contribute to the loss later.
+
+ def __init__(
+ self,
+ token_classification_task: TokenClassificationTask,
+ data_dir: str,
+ tokenizer: PreTrainedTokenizer,
+ labels: List[str],
+ model_type: str,
+ max_seq_length: Optional[int] = None,
+ overwrite_cache=False,
+ mode: Split = Split.train,
+ ):
+ # Load data features from cache or dataset file
+ cached_features_file = os.path.join(
+ data_dir,
+ "cached_{}_{}_{}".format(mode.value, tokenizer.__class__.__name__, str(max_seq_length)),
+ )
+
+ # Make sure only the first process in distributed training processes the dataset,
+ # and the others will use the cache.
+ lock_path = cached_features_file + ".lock"
+ with FileLock(lock_path):
+ if os.path.exists(cached_features_file) and not overwrite_cache:
+ logger.info(f"Loading features from cached file {cached_features_file}")
+ self.features = torch.load(cached_features_file)
+ else:
+ logger.info(f"Creating features from dataset file at {data_dir}")
+ examples = token_classification_task.read_examples_from_file(data_dir, mode)
+ # TODO clean up all this to leverage built-in features of tokenizers
+ self.features = token_classification_task.convert_examples_to_features(
+ examples,
+ labels,
+ max_seq_length,
+ tokenizer,
+ cls_token_at_end=bool(model_type in ["xlnet"]),
+ # xlnet has a cls token at the end
+ cls_token=tokenizer.cls_token,
+ cls_token_segment_id=2 if model_type in ["xlnet"] else 0,
+ sep_token=tokenizer.sep_token,
+ sep_token_extra=False,
+ # roberta uses an extra separator b/w pairs of sentences, cf. github.com/pytorch/fairseq/commit/1684e166e3da03f5b600dbb7855cb98ddfcd0805
+ pad_on_left=bool(tokenizer.padding_side == "left"),
+ pad_token=tokenizer.pad_token_id,
+ pad_token_segment_id=tokenizer.pad_token_type_id,
+ pad_token_label_id=self.pad_token_label_id,
+ )
+ logger.info(f"Saving features into cached file {cached_features_file}")
+ torch.save(self.features, cached_features_file)
+
+ def __len__(self):
+ return len(self.features)
+
+ def __getitem__(self, i) -> InputFeatures:
+ return self.features[i]
+
+
+if is_tf_available():
+ import tensorflow as tf
+
+ class TFTokenClassificationDataset:
+ """
+ This will be superseded by a framework-agnostic approach
+ soon.
+ """
+
+ features: List[InputFeatures]
+ pad_token_label_id: int = -100
+ # Use cross entropy ignore_index as padding label id so that only
+ # real label ids contribute to the loss later.
+
+ def __init__(
+ self,
+ token_classification_task: TokenClassificationTask,
+ data_dir: str,
+ tokenizer: PreTrainedTokenizer,
+ labels: List[str],
+ model_type: str,
+ max_seq_length: Optional[int] = None,
+ overwrite_cache=False,
+ mode: Split = Split.train,
+ ):
+ examples = token_classification_task.read_examples_from_file(data_dir, mode)
+ # TODO clean up all this to leverage built-in features of tokenizers
+ self.features = token_classification_task.convert_examples_to_features(
+ examples,
+ labels,
+ max_seq_length,
+ tokenizer,
+ cls_token_at_end=bool(model_type in ["xlnet"]),
+ # xlnet has a cls token at the end
+ cls_token=tokenizer.cls_token,
+ cls_token_segment_id=2 if model_type in ["xlnet"] else 0,
+ sep_token=tokenizer.sep_token,
+ sep_token_extra=False,
+ # roberta uses an extra separator b/w pairs of sentences, cf. github.com/pytorch/fairseq/commit/1684e166e3da03f5b600dbb7855cb98ddfcd0805
+ pad_on_left=bool(tokenizer.padding_side == "left"),
+ pad_token=tokenizer.pad_token_id,
+ pad_token_segment_id=tokenizer.pad_token_type_id,
+ pad_token_label_id=self.pad_token_label_id,
+ )
+
+ def gen():
+ for ex in self.features:
+ if ex.token_type_ids is None:
+ yield (
+ {"input_ids": ex.input_ids, "attention_mask": ex.attention_mask},
+ ex.label_ids,
+ )
+ else:
+ yield (
+ {
+ "input_ids": ex.input_ids,
+ "attention_mask": ex.attention_mask,
+ "token_type_ids": ex.token_type_ids,
+ },
+ ex.label_ids,
+ )
+
+ if "token_type_ids" not in tokenizer.model_input_names:
+ self.dataset = tf.data.Dataset.from_generator(
+ gen,
+ ({"input_ids": tf.int32, "attention_mask": tf.int32}, tf.int64),
+ (
+ {"input_ids": tf.TensorShape([None]), "attention_mask": tf.TensorShape([None])},
+ tf.TensorShape([None]),
+ ),
+ )
+ else:
+ self.dataset = tf.data.Dataset.from_generator(
+ gen,
+ ({"input_ids": tf.int32, "attention_mask": tf.int32, "token_type_ids": tf.int32}, tf.int64),
+ (
+ {
+ "input_ids": tf.TensorShape([None]),
+ "attention_mask": tf.TensorShape([None]),
+ "token_type_ids": tf.TensorShape([None]),
+ },
+ tf.TensorShape([None]),
+ ),
+ )
+
+ def get_dataset(self):
+ self.dataset = self.dataset.apply(tf.data.experimental.assert_cardinality(len(self.features)))
+
+ return self.dataset
+
+ def __len__(self):
+ return len(self.features)
+
+ def __getitem__(self, i) -> InputFeatures:
+ return self.features[i]
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..4eba1d03aebc8b40a015d04c56e67b0c138f6084
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/README.md
@@ -0,0 +1,20 @@
+# Using the `modular_converter` linter
+
+`pip install libcst` is a must!
+
+# `sh examples/modular-transformers/convert_examples.sh` to get the converted outputs
+
+The modular converter is a new `linter` specific to `transformers`. It allows us to unpack inheritance in python to convert a modular file like `modular_gemma.py` into a `single model single file`.
+
+Examples of possible usage are available in the `examples/modular-transformers`, or `modular_gemma` for a full model usage.
+
+`python utils/modular_model_converter.py --files_to_parse "/Users/arthurzucker/Work/transformers/examples/modular-transformers/modular_my_new_model2.py"`
+
+## How it works
+We use the `libcst` parser to produce an AST representation of the `modular_xxx.py` file. For any imports that are made from `transformers.models.modeling_xxxx` we parse the source code of that module, and build a class dependency mapping, which allows us to unpack the modularerence dependencies.
+
+The code from the `modular` file and the class dependency mapping are "merged" to produce the single model single file.
+We use ruff to automatically remove the potential duplicate imports.
+
+## Why we use libcst instead of the native AST?
+AST is super powerful, but it does not keep the `docstring`, `comment` or code formatting. Thus we decided to go with `libcst`
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/configuration_dummy.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/configuration_dummy.py
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/configuration_my_new_model.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/configuration_my_new_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..59637e02d3f11cb7fe511f71a7220b4d948f7a66
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/configuration_my_new_model.py
@@ -0,0 +1,206 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from examples/modular-transformers/modular_my_new_model.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_my_new_model.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+
+from ...configuration_utils import PretrainedConfig
+from ...modeling_rope_utils import rope_config_validation
+
+
+class MyNewModelConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`MyNewModelModel`]. It is used to instantiate an MyNewModel
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the MyNewModel-7B.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 32000):
+ Vocabulary size of the MyNewModel model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`MyNewModelModel`]
+ hidden_size (`int`, *optional*, defaults to 4096):
+ Dimension of the hidden representations.
+ intermediate_size (`int`, *optional*, defaults to 11008):
+ Dimension of the MLP representations.
+ num_hidden_layers (`int`, *optional*, defaults to 32):
+ Number of hidden layers in the Transformer decoder.
+ num_attention_heads (`int`, *optional*, defaults to 32):
+ Number of attention heads for each attention layer in the Transformer decoder.
+ num_key_value_heads (`int`, *optional*):
+ This is the number of key_value heads that should be used to implement Grouped Query Attention. If
+ `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if
+ `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When
+ converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed
+ by meanpooling all the original heads within that group. For more details checkout [this
+ paper](https://arxiv.org/pdf/2305.13245.pdf). If it is not specified, will default to
+ `num_attention_heads`.
+ hidden_act (`str` or `function`, *optional*, defaults to `"silu"`):
+ The non-linear activation function (function or string) in the decoder.
+ max_position_embeddings (`int`, *optional*, defaults to 2048):
+ The maximum sequence length that this model might ever be used with. MyNewModel 1 supports up to 2048 tokens,
+ MyNewModel 2 up to 4096, CodeLlama up to 16384.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ rms_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the rms normalization layers.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models). Only
+ relevant if `config.is_decoder=True`.
+ pad_token_id (`int`, *optional*):
+ Padding token id.
+ bos_token_id (`int`, *optional*, defaults to 1):
+ Beginning of stream token id.
+ eos_token_id (`int`, *optional*, defaults to 2):
+ End of stream token id.
+ pretraining_tp (`int`, *optional*, defaults to 1):
+ Experimental feature. Tensor parallelism rank used during pretraining. Please refer to [this
+ document](https://huggingface.co/docs/transformers/main/perf_train_gpu_many#tensor-parallelism) to
+ understand more about it. This value is necessary to ensure exact reproducibility of the pretraining
+ results. Please refer to [this issue](https://github.com/pytorch/pytorch/issues/76232).
+ tie_word_embeddings (`bool`, *optional*, defaults to `False`):
+ Whether to tie weight embeddings
+ rope_theta (`float`, *optional*, defaults to 10000.0):
+ The base period of the RoPE embeddings.
+ rope_scaling (`Dict`, *optional*):
+ Dictionary containing the scaling configuration for the RoPE embeddings. NOTE: if you apply new rope type
+ and you expect the model to work on longer `max_position_embeddings`, we recommend you to update this value
+ accordingly.
+ Expected contents:
+ `rope_type` (`str`):
+ The sub-variant of RoPE to use. Can be one of ['default', 'linear', 'dynamic', 'yarn', 'longrope',
+ 'my_new_model3'], with 'default' being the original RoPE implementation.
+ `factor` (`float`, *optional*):
+ Used with all rope types except 'default'. The scaling factor to apply to the RoPE embeddings. In
+ most scaling types, a `factor` of x will enable the model to handle sequences of length x *
+ original maximum pre-trained length.
+ `original_max_position_embeddings` (`int`, *optional*):
+ Used with 'dynamic', 'longrope' and 'my_new_model3'. The original max position embeddings used during
+ pretraining.
+ `attention_factor` (`float`, *optional*):
+ Used with 'yarn' and 'longrope'. The scaling factor to be applied on the attention
+ computation. If unspecified, it defaults to value recommended by the implementation, using the
+ `factor` field to infer the suggested value.
+ `beta_fast` (`float`, *optional*):
+ Only used with 'yarn'. Parameter to set the boundary for extrapolation (only) in the linear
+ ramp function. If unspecified, it defaults to 32.
+ `beta_slow` (`float`, *optional*):
+ Only used with 'yarn'. Parameter to set the boundary for interpolation (only) in the linear
+ ramp function. If unspecified, it defaults to 1.
+ `short_factor` (`List[float]`, *optional*):
+ Only used with 'longrope'. The scaling factor to be applied to short contexts (<
+ `original_max_position_embeddings`). Must be a list of numbers with the same length as the hidden
+ size divided by the number of attention heads divided by 2
+ `long_factor` (`List[float]`, *optional*):
+ Only used with 'longrope'. The scaling factor to be applied to long contexts (<
+ `original_max_position_embeddings`). Must be a list of numbers with the same length as the hidden
+ size divided by the number of attention heads divided by 2
+ `low_freq_factor` (`float`, *optional*):
+ Only used with 'my_new_model3'. Scaling factor applied to low frequency components of the RoPE
+ `high_freq_factor` (`float`, *optional*):
+ Only used with 'my_new_model3'. Scaling factor applied to high frequency components of the RoPE
+ attention_bias (`bool`, *optional*, defaults to `False`):
+ Whether to use a bias in the query, key, value and output projection layers during self-attention.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ mlp_bias (`bool`, *optional*, defaults to `False`):
+ Whether to use a bias in up_proj, down_proj and gate_proj layers in the MLP layers.
+ head_dim (`int`, *optional*):
+ The attention head dimension. If None, it will default to hidden_size // num_attention_heads
+
+ ```python
+ >>> from transformers import MyNewModelModel, MyNewModelConfig
+
+ >>> # Initializing a MyNewModel my_new_model-7b style configuration
+ >>> configuration = MyNewModelConfig()
+
+ >>> # Initializing a model from the my_new_model-7b style configuration
+ >>> model = MyNewModelModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```
+ new_param (`int`, *optional*, defaults to `False`):
+ A fun new parameter
+ """
+
+ model_type = "my_new_model"
+ keys_to_ignore_at_inference = ["past_key_values"]
+ # Default tensor parallel plan for base model `MyNewModelModel`
+ base_model_tp_plan = {
+ "layers.*.self_attn.q_proj": "colwise",
+ "layers.*.self_attn.k_proj": "colwise",
+ "layers.*.self_attn.v_proj": "colwise",
+ "layers.*.self_attn.o_proj": "rowwise",
+ "layers.*.mlp.gate_proj": "colwise",
+ "layers.*.mlp.up_proj": "colwise",
+ "layers.*.mlp.down_proj": "rowwise",
+ }
+
+ def __init__(
+ self,
+ vocab_size=32000,
+ hidden_size=4096,
+ intermediate_size=11008,
+ num_hidden_layers=32,
+ num_attention_heads=32,
+ num_key_value_heads=None,
+ hidden_act="silu",
+ max_position_embeddings=2048,
+ initializer_range=0.02,
+ rms_norm_eps=1e-6,
+ use_cache=True,
+ pad_token_id=None,
+ bos_token_id=1,
+ eos_token_id=2,
+ pretraining_tp=1,
+ tie_word_embeddings=False,
+ rope_theta=10000.0,
+ rope_scaling=None,
+ attention_bias=False,
+ attention_dropout=0.0,
+ mlp_bias=True,
+ head_dim=None,
+ new_param=0,
+ **kwargs,
+ ):
+ super().__init__(
+ pad_token_id=pad_token_id,
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ tie_word_embeddings=tie_word_embeddings,
+ **kwargs,
+ )
+ self.vocab_size = vocab_size
+ self.max_position_embeddings = max_position_embeddings
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+
+ # for backward compatibility
+ if num_key_value_heads is None:
+ num_key_value_heads = num_attention_heads
+
+ self.num_key_value_heads = num_key_value_heads
+ self.hidden_act = hidden_act
+ self.initializer_range = initializer_range
+ self.rms_norm_eps = rms_norm_eps
+ self.pretraining_tp = pretraining_tp
+ self.use_cache = use_cache
+ self.rope_theta = rope_theta
+ self.rope_scaling = rope_scaling
+ self.attention_bias = attention_bias
+ self.attention_dropout = attention_dropout
+ self.mlp_bias = mlp_bias
+ self.head_dim = head_dim if head_dim is not None else self.hidden_size // self.num_attention_heads
+ # Validate the correctness of rotary position embeddings parameters
+ # BC: if there is a 'type' field, copy it it to 'rope_type'.
+ if self.rope_scaling is not None and "type" in self.rope_scaling:
+ self.rope_scaling["rope_type"] = self.rope_scaling["type"]
+ rope_config_validation(self)
+ self.new_param = new_param
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/configuration_my_new_model2.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/configuration_my_new_model2.py
new file mode 100644
index 0000000000000000000000000000000000000000..eddd7fe47973ef1847177cf7b9523333569d16ea
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/configuration_my_new_model2.py
@@ -0,0 +1,108 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from examples/modular-transformers/modular_my_new_model2.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_my_new_model2.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+
+from ...configuration_utils import PretrainedConfig
+from ...modeling_rope_utils import rope_config_validation
+
+
+class MyNewModel2Config(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`GemmaModel`]. It is used to instantiate an Gemma
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the Gemma-7B.
+ e.g. [google/gemma-7b](https://huggingface.co/google/gemma-7b)
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+ Args:
+ vocab_size (`int`, *optional*, defaults to 256000):
+ Vocabulary size of the Gemma model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`GemmaModel`]
+ ```python
+ >>> from transformers import GemmaModel, GemmaConfig
+ >>> # Initializing a Gemma gemma-7b style configuration
+ >>> configuration = GemmaConfig()
+ >>> # Initializing a model from the gemma-7b style configuration
+ >>> model = GemmaModel(configuration)
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "my_new_model2"
+ keys_to_ignore_at_inference = ["past_key_values"]
+ # Default tensor parallel plan for base model `MyNewModel2Model`
+ base_model_tp_plan = {
+ "layers.*.self_attn.q_proj": "colwise",
+ "layers.*.self_attn.k_proj": "colwise",
+ "layers.*.self_attn.v_proj": "colwise",
+ "layers.*.self_attn.o_proj": "rowwise",
+ "layers.*.mlp.gate_proj": "colwise",
+ "layers.*.mlp.up_proj": "colwise",
+ "layers.*.mlp.down_proj": "rowwise",
+ }
+
+ def __init__(
+ self,
+ vocab_size=32000,
+ hidden_size=4096,
+ intermediate_size=11008,
+ num_hidden_layers=32,
+ num_attention_heads=32,
+ num_key_value_heads=None,
+ hidden_act="silu",
+ max_position_embeddings=2048,
+ initializer_range=0.02,
+ rms_norm_eps=1e-6,
+ use_cache=True,
+ pad_token_id=None,
+ bos_token_id=1,
+ eos_token_id=2,
+ pretraining_tp=1,
+ tie_word_embeddings=False,
+ rope_theta=10000.0,
+ rope_scaling=None,
+ attention_bias=False,
+ attention_dropout=0.0,
+ mlp_bias=False,
+ head_dim=None,
+ **kwargs,
+ ):
+ self.vocab_size = vocab_size
+ self.max_position_embeddings = max_position_embeddings
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+
+ # for backward compatibility
+ if num_key_value_heads is None:
+ num_key_value_heads = num_attention_heads
+
+ self.num_key_value_heads = num_key_value_heads
+ self.hidden_act = hidden_act
+ self.initializer_range = initializer_range
+ self.rms_norm_eps = rms_norm_eps
+ self.pretraining_tp = pretraining_tp
+ self.use_cache = use_cache
+ self.rope_theta = rope_theta
+ self.rope_scaling = rope_scaling
+ self.attention_bias = attention_bias
+ self.attention_dropout = attention_dropout
+ self.mlp_bias = mlp_bias
+ self.head_dim = head_dim if head_dim is not None else self.hidden_size // self.num_attention_heads
+ # Validate the correctness of rotary position embeddings parameters
+ # BC: if there is a 'type' field, copy it it to 'rope_type'.
+ if self.rope_scaling is not None and "type" in self.rope_scaling:
+ self.rope_scaling["rope_type"] = self.rope_scaling["type"]
+ rope_config_validation(self)
+
+ super().__init__(
+ pad_token_id=pad_token_id,
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ tie_word_embeddings=tie_word_embeddings,
+ **kwargs,
+ )
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/configuration_new_model.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/configuration_new_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..4d164fe3e75f1847cc65cfe3dbf69d7a1701e861
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/configuration_new_model.py
@@ -0,0 +1,133 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from examples/modular-transformers/modular_new_model.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_new_model.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# Example where we only want to overwrite the defaults of an init
+
+from ...configuration_utils import PretrainedConfig
+
+
+class NewModelConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`NewModelModel`]. It is used to instantiate an NewModel
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the NewModel-7B.
+ e.g. [google/new_model-7b](https://huggingface.co/google/new_model-7b)
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+ Args:
+ vocab_size (`int`, *optional*, defaults to 256000):
+ Vocabulary size of the NewModel model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`NewModelModel`]
+ hidden_size (`int`, *optional*, defaults to 3072):
+ Dimension of the hidden representations.
+ intermediate_size (`int`, *optional*, defaults to 24576):
+ Dimension of the MLP representations.
+ num_hidden_layers (`int`, *optional*, defaults to 28):
+ Number of hidden layers in the Transformer decoder.
+ num_attention_heads (`int`, *optional*, defaults to 16):
+ Number of attention heads for each attention layer in the Transformer decoder.
+ num_key_value_heads (`int`, *optional*, defaults to 16):
+ This is the number of key_value heads that should be used to implement Grouped Query Attention. If
+ `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if
+ `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When
+ converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed
+ by meanpooling all the original heads within that group. For more details checkout [this
+ paper](https://arxiv.org/pdf/2305.13245.pdf). If it is not specified, will default to
+ `num_attention_heads`.
+ head_dim (`int`, *optional*, defaults to 256):
+ The attention head dimension.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`):
+ The legacy activation function. It is overwritten by the `hidden_activation`.
+ hidden_activation (`str` or `function`, *optional*):
+ The non-linear activation function (function or string) in the decoder. Will default to `"gelu_pytorch_tanh"`
+ if not specified. `"gelu_pytorch_tanh"` uses an approximation of the `"gelu"` activation function.
+ max_position_embeddings (`int`, *optional*, defaults to 8192):
+ The maximum sequence length that this model might ever be used with.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ rms_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the rms normalization layers.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models). Only
+ relevant if `config.is_decoder=True`.
+ pad_token_id (`int`, *optional*, defaults to 0):
+ Padding token id.
+ eos_token_id (`int`, *optional*, defaults to 1):
+ End of stream token id.
+ bos_token_id (`int`, *optional*, defaults to 2):
+ Beginning of stream token id.
+ tie_word_embeddings (`bool`, *optional*, defaults to `True`):
+ Whether to tie weight embeddings
+ rope_theta (`float`, *optional*, defaults to 10000.0):
+ The base period of the RoPE embeddings.
+ attention_bias (`bool`, defaults to `False`, *optional*, defaults to `False`):
+ Whether to use a bias in the query, key, value and output projection layers during self-attention.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ ```python
+ >>> from transformers import NewModelModel, NewModelConfig
+ >>> # Initializing a NewModel new_model-7b style configuration
+ >>> configuration = NewModelConfig()
+ >>> # Initializing a model from the new_model-7b style configuration
+ >>> model = NewModelModel(configuration)
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "new_model"
+ keys_to_ignore_at_inference = ["past_key_values"]
+
+ def __init__(
+ self,
+ vocab_size=256030,
+ hidden_size=64,
+ intermediate_size=90,
+ num_hidden_layers=28,
+ num_attention_heads=16,
+ num_key_value_heads=16,
+ head_dim=256,
+ hidden_act="gelu_pytorch_tanh",
+ hidden_activation=None,
+ max_position_embeddings=1500,
+ initializer_range=0.02,
+ rms_norm_eps=1e-6,
+ use_cache=True,
+ pad_token_id=0,
+ eos_token_id=1,
+ bos_token_id=2,
+ tie_word_embeddings=True,
+ rope_theta=10000.0,
+ attention_bias=False,
+ attention_dropout=0.0,
+ **kwargs,
+ ):
+ super().__init__(
+ pad_token_id=pad_token_id,
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ tie_word_embeddings=tie_word_embeddings,
+ **kwargs,
+ )
+ self.vocab_size = vocab_size
+ self.max_position_embeddings = max_position_embeddings
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.head_dim = head_dim
+ self.num_key_value_heads = num_key_value_heads
+ self.hidden_act = hidden_act
+ self.hidden_activation = hidden_activation
+ self.initializer_range = initializer_range
+ self.rms_norm_eps = rms_norm_eps
+ self.use_cache = use_cache
+ self.rope_theta = rope_theta
+ self.attention_bias = attention_bias
+ self.attention_dropout = attention_dropout
+
+ @property
+ def num_heads(self):
+ return self.num_attention_heads
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/configuration_super.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/configuration_super.py
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/convert_examples.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/convert_examples.sh
new file mode 100644
index 0000000000000000000000000000000000000000..49666ab1154d33c0d06930c01aa6d43b4a963d74
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/convert_examples.sh
@@ -0,0 +1,10 @@
+#!/bin/bash
+
+# Iterate over each file in the current directory
+for file in examples/modular-transformers/modular_*; do
+ # Check if it's a regular file
+ if [ -f "$file" ]; then
+ # Call the Python script with the file name as an argument
+ python utils/modular_model_converter.py --files_to_parse "$file"
+ fi
+done
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/image_processing_new_imgproc_model.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/image_processing_new_imgproc_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..f3ab1772ec59e982ec24bfdb986af8485d1ffc22
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/image_processing_new_imgproc_model.py
@@ -0,0 +1,287 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from examples/modular-transformers/modular_new_imgproc_model.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_new_imgproc_model.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+from typing import Dict, List, Optional, Union
+
+import numpy as np
+import torch
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict
+from ...image_transforms import convert_to_rgb, resize, to_channel_dimension_format
+from ...image_utils import (
+ OPENAI_CLIP_MEAN,
+ OPENAI_CLIP_STD,
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ make_list_of_images,
+ to_numpy_array,
+ valid_images,
+ validate_preprocess_arguments,
+)
+from ...utils import TensorType, filter_out_non_signature_kwargs, is_vision_available, logging
+
+
+if is_vision_available():
+ import PIL
+
+
+logger = logging.get_logger(__name__)
+
+
+class ImgprocModelImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a IMGPROC_MODEL image processor.
+
+ Args:
+ do_resize (`bool`, *optional*, defaults to `True`):
+ Whether to resize the image's (height, width) dimensions to the specified `size`. Can be overridden by the
+ `do_resize` parameter in the `preprocess` method.
+ size (`dict`, *optional*, defaults to `{"height": 384, "width": 384}`):
+ Size of the output image after resizing. Can be overridden by the `size` parameter in the `preprocess`
+ method.
+ resample (`PILImageResampling`, *optional*, defaults to `Resampling.BICUBIC`):
+ Resampling filter to use if resizing the image. Only has an effect if `do_resize` is set to `True`. Can be
+ overridden by the `resample` parameter in the `preprocess` method.
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the
+ `do_rescale` parameter in the `preprocess` method.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Scale factor to use if rescaling the image. Only has an effect if `do_rescale` is set to `True`. Can be
+ overridden by the `rescale_factor` parameter in the `preprocess` method.
+ do_normalize (`bool`, *optional*, defaults to `True`):
+ Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess`
+ method. Can be overridden by the `do_normalize` parameter in the `preprocess` method.
+ image_mean (`float` or `List[float]`, *optional*, defaults to `IMAGENET_STANDARD_MEAN`):
+ Mean to use if normalizing the image. This is a float or list of floats the length of the number of
+ channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method. Can be
+ overridden by the `image_mean` parameter in the `preprocess` method.
+ image_std (`float` or `List[float]`, *optional*, defaults to `IMAGENET_STANDARD_STD`):
+ Standard deviation to use if normalizing the image. This is a float or list of floats the length of the
+ number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method.
+ Can be overridden by the `image_std` parameter in the `preprocess` method.
+ do_convert_rgb (`bool`, *optional*, defaults to `True`):
+ Whether to convert the image to RGB.
+ """
+
+ model_input_names = ["pixel_values"]
+
+ def __init__(
+ self,
+ do_resize: bool = True,
+ size: Dict[str, int] = None,
+ resample: PILImageResampling = PILImageResampling.BICUBIC,
+ do_rescale: bool = True,
+ rescale_factor: Union[int, float] = 1 / 255,
+ do_normalize: bool = True,
+ image_mean: Optional[Union[float, List[float]]] = None,
+ image_std: Optional[Union[float, List[float]]] = None,
+ do_convert_rgb: bool = True,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+ size = size if size is not None else {"height": 384, "width": 384}
+ size = get_size_dict(size, default_to_square=True)
+
+ self.do_resize = do_resize
+ self.size = size
+ self.resample = resample
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.do_normalize = do_normalize
+ self.image_mean = image_mean if image_mean is not None else OPENAI_CLIP_MEAN
+ self.image_std = image_std if image_std is not None else OPENAI_CLIP_STD
+ self.do_convert_rgb = do_convert_rgb
+
+ def resize(
+ self,
+ image: np.ndarray,
+ size: Dict[str, int],
+ resample: PILImageResampling = PILImageResampling.BICUBIC,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ) -> np.ndarray:
+ """
+ Resize an image to `(size["height"], size["width"])`.
+
+ Args:
+ image (`np.ndarray`):
+ Image to resize.
+ size (`Dict[str, int]`):
+ Dictionary in the format `{"height": int, "width": int}` specifying the size of the output image.
+ resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BICUBIC`):
+ `PILImageResampling` filter to use when resizing the image e.g. `PILImageResampling.BICUBIC`.
+ data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the output image. If unset, the channel dimension format of the input
+ image is used. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+
+ Returns:
+ `np.ndarray`: The resized image.
+ """
+ size = get_size_dict(size)
+ if "height" not in size or "width" not in size:
+ raise ValueError(f"The `size` dictionary must contain the keys `height` and `width`. Got {size.keys()}")
+ output_size = (size["height"], size["width"])
+ return resize(
+ image,
+ size=output_size,
+ resample=resample,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ **kwargs,
+ )
+
+ @filter_out_non_signature_kwargs()
+ def preprocess(
+ self,
+ images: ImageInput,
+ do_resize: Optional[bool] = None,
+ size: Optional[Dict[str, int]] = None,
+ resample: PILImageResampling = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, List[float]]] = None,
+ image_std: Optional[Union[float, List[float]]] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ do_convert_rgb: bool = None,
+ data_format: ChannelDimension = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> PIL.Image.Image:
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ images (`ImageInput`):
+ Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If
+ passing in images with pixel values between 0 and 1, set `do_rescale=False`.
+ do_resize (`bool`, *optional*, defaults to `self.do_resize`):
+ Whether to resize the image.
+ size (`Dict[str, int]`, *optional*, defaults to `self.size`):
+ Controls the size of the image after `resize`. The shortest edge of the image is resized to
+ `size["shortest_edge"]` whilst preserving the aspect ratio. If the longest edge of this resized image
+ is > `int(size["shortest_edge"] * (1333 / 800))`, then the image is resized again to make the longest
+ edge equal to `int(size["shortest_edge"] * (1333 / 800))`.
+ resample (`PILImageResampling`, *optional*, defaults to `self.resample`):
+ Resampling filter to use if resizing the image. Only has an effect if `do_resize` is set to `True`.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image values between [0 - 1].
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_normalize (`bool`, *optional*, defaults to `self.do_normalize`):
+ Whether to normalize the image.
+ image_mean (`float` or `List[float]`, *optional*, defaults to `self.image_mean`):
+ Image mean to normalize the image by if `do_normalize` is set to `True`.
+ image_std (`float` or `List[float]`, *optional*, defaults to `self.image_std`):
+ Image standard deviation to normalize the image by if `do_normalize` is set to `True`.
+ do_convert_rgb (`bool`, *optional*, defaults to `self.do_convert_rgb`):
+ Whether to convert the image to RGB.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - Unset: Use the channel dimension format of the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+ do_resize = do_resize if do_resize is not None else self.do_resize
+ resample = resample if resample is not None else self.resample
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ do_normalize = do_normalize if do_normalize is not None else self.do_normalize
+ image_mean = image_mean if image_mean is not None else self.image_mean
+ image_std = image_std if image_std is not None else self.image_std
+ do_convert_rgb = do_convert_rgb if do_convert_rgb is not None else self.do_convert_rgb
+
+ size = size if size is not None else self.size
+ size = get_size_dict(size, default_to_square=False)
+
+ images = make_list_of_images(images)
+
+ if not valid_images(images):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+
+ validate_preprocess_arguments(
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ )
+ # PIL RGBA images are converted to RGB
+ if do_convert_rgb:
+ images = [convert_to_rgb(image) for image in images]
+
+ # All transformations expect numpy arrays.
+ images = [to_numpy_array(image) for image in images]
+
+ if do_rescale and is_scaled_image(images[0]):
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ # We assume that all images have the same channel dimension format.
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ if do_resize:
+ images = [
+ self.resize(image=image, size=size, resample=resample, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ if do_rescale:
+ images = [
+ self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ if do_normalize:
+ images = [
+ self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ images = [
+ to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) for image in images
+ ]
+
+ encoded_outputs = BatchFeature(data={"pixel_values": images}, tensor_type=return_tensors)
+
+ return encoded_outputs
+
+ def new_image_processing_method(self, pixel_values: torch.FloatTensor):
+ return pixel_values / 2
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_dummy.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_dummy.py
new file mode 100644
index 0000000000000000000000000000000000000000..382b87bd38471e1ba7bc927138e2fb8646cdfabb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_dummy.py
@@ -0,0 +1,710 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from examples/modular-transformers/modular_dummy.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_dummy.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+from typing import Callable, Optional, Tuple, Union
+
+import torch
+from torch import nn
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache, StaticCache
+from ...modeling_attn_mask_utils import AttentionMaskConverter
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_outputs import BaseModelOutputWithPast
+from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import add_start_docstrings, add_start_docstrings_to_model_forward, logging
+from .configuration_dummy import DummyConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class DummyRMSNorm(nn.Module):
+ def __init__(self, hidden_size, eps=1e-6):
+ """
+ DummyRMSNorm is equivalent to T5LayerNorm
+ """
+ super().__init__()
+ self.weight = nn.Parameter(torch.ones(hidden_size))
+ self.variance_epsilon = eps
+
+ def forward(self, hidden_states):
+ input_dtype = hidden_states.dtype
+ hidden_states = hidden_states.to(torch.float32)
+ variance = hidden_states.pow(2).mean(-1, keepdim=True)
+ hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon)
+ return self.weight * hidden_states.to(input_dtype)
+
+ def extra_repr(self):
+ return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}"
+
+
+class DummyRotaryEmbedding(nn.Module):
+ def __init__(
+ self,
+ config: DummyConfig,
+ device=None,
+ ):
+ super().__init__()
+ self.rope_kwargs = {}
+ # BC: "rope_type" was originally "type"
+ if hasattr(config, "rope_scaling") and config.rope_scaling is not None:
+ self.rope_type = config.rope_scaling.get("rope_type", config.rope_scaling.get("type"))
+ else:
+ self.rope_type = "default"
+ self.max_seq_len_cached = config.max_position_embeddings
+ self.original_max_seq_len = config.max_position_embeddings
+
+ self.config = config
+ self.rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type]
+
+ inv_freq, self.attention_scaling = self.rope_init_fn(self.config, device, **self.rope_kwargs)
+ self.register_buffer("inv_freq", inv_freq, persistent=False)
+ self.original_inv_freq = self.inv_freq
+
+ def _dynamic_frequency_update(self, position_ids, device):
+ """
+ dynamic RoPE layers should recompute `inv_freq` in the following situations:
+ 1 - growing beyond the cached sequence length (allow scaling)
+ 2 - the current sequence length is in the original scale (avoid losing precision with small sequences)
+ """
+ seq_len = torch.max(position_ids) + 1
+ if seq_len > self.max_seq_len_cached: # growth
+ inv_freq, self.attention_scaling = self.rope_init_fn(
+ self.config, device, seq_len=seq_len, **self.rope_kwargs
+ )
+ self.register_buffer("inv_freq", inv_freq, persistent=False) # TODO joao: may break with compilation
+ self.max_seq_len_cached = seq_len
+
+ if seq_len < self.original_max_seq_len and self.max_seq_len_cached > self.original_max_seq_len: # reset
+ self.register_buffer("inv_freq", self.original_inv_freq, persistent=False)
+ self.max_seq_len_cached = self.original_max_seq_len
+
+ @torch.no_grad()
+ def forward(self, x, position_ids):
+ if "dynamic" in self.rope_type:
+ self._dynamic_frequency_update(position_ids, device=x.device)
+
+ # Core RoPE block
+ inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1)
+ position_ids_expanded = position_ids[:, None, :].float()
+ # Force float32 (see https://github.com/huggingface/transformers/pull/29285)
+ device_type = x.device.type
+ device_type = device_type if isinstance(device_type, str) and device_type != "mps" else "cpu"
+ with torch.autocast(device_type=device_type, enabled=False):
+ freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2)
+ emb = torch.cat((freqs, freqs), dim=-1)
+ cos = emb.cos()
+ sin = emb.sin()
+
+ # Advanced RoPE types (e.g. yarn) apply a post-processing scaling factor, equivalent to scaling attention
+ cos = cos * self.attention_scaling
+ sin = sin * self.attention_scaling
+
+ return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype)
+
+
+class DummyMLP(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.hidden_size = config.hidden_size
+ self.intermediate_size = config.intermediate_size
+ self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=config.mlp_bias)
+ self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=config.mlp_bias)
+ self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=config.mlp_bias)
+ self.act_fn = ACT2FN[config.hidden_act]
+
+ def forward(self, x):
+ down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x))
+ return down_proj
+
+
+def rotate_half(x):
+ """Rotates half the hidden dims of the input."""
+ x1 = x[..., : x.shape[-1] // 4]
+ x2 = x[..., x.shape[-1] // 4 :]
+ return torch.cat((-x2, x1), dim=-1)
+
+
+def apply_rotary_pos_emb(q, k, cos, sin, position_ids=None, unsqueeze_dim=1):
+ """Applies Rotary Position Embedding to the query and key tensors.
+
+ Args:
+ q (`torch.Tensor`): The query tensor.
+ k (`torch.Tensor`): The key tensor.
+ cos (`torch.Tensor`): The cosine part of the rotary embedding.
+ sin (`torch.Tensor`): The sine part of the rotary embedding.
+ position_ids (`torch.Tensor`, *optional*):
+ Deprecated and unused.
+ unsqueeze_dim (`int`, *optional*, defaults to 1):
+ The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and
+ sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note
+ that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and
+ k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes
+ cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have
+ the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2.
+ Returns:
+ `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding.
+ """
+ cos = cos.unsqueeze(unsqueeze_dim)
+ sin = sin.unsqueeze(unsqueeze_dim)
+ q_embed = (q * cos) + (rotate_half(q) * sin)
+ k_embed = (k * cos) + (rotate_half(k) * sin)
+ return q_embed, k_embed
+
+
+def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor:
+ """
+ This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch,
+ num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim)
+ """
+ batch, num_key_value_heads, slen, head_dim = hidden_states.shape
+ if n_rep == 1:
+ return hidden_states
+ hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim)
+ return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim)
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ key_states = repeat_kv(key, module.num_key_value_groups)
+ value_states = repeat_kv(value, module.num_key_value_groups)
+
+ attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling
+ if attention_mask is not None:
+ causal_mask = attention_mask[:, :, :, : key_states.shape[-2]]
+ attn_weights = attn_weights + causal_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value_states)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class DummyAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config: DummyConfig, layer_idx: int):
+ super().__init__()
+ self.config = config
+ self.layer_idx = layer_idx
+ self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads)
+ self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads
+ self.scaling = self.head_dim**-0.5
+ self.attention_dropout = config.attention_dropout
+ self.is_causal = True
+
+ self.q_proj = nn.Linear(
+ config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.k_proj = nn.Linear(
+ config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.v_proj = nn.Linear(
+ config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.o_proj = nn.Linear(
+ config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_bias
+ )
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ position_embeddings: Tuple[torch.Tensor, torch.Tensor],
+ attention_mask: Optional[torch.Tensor],
+ past_key_value: Optional[Cache] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> Tuple[torch.Tensor, Optional[torch.Tensor], Optional[Tuple[torch.Tensor]]]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+
+ query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ cos, sin = position_embeddings
+ query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin)
+
+ if past_key_value is not None:
+ # sin and cos are specific to RoPE models; cache_position needed for the static cache
+ cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position}
+ key_states, value_states = past_key_value.update(key_states, value_states, self.layer_idx, cache_kwargs)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ if self.config._attn_implementation == "sdpa" and kwargs.get("output_attentions", False):
+ logger.warning_once(
+ "`torch.nn.functional.scaled_dot_product_attention` does not support `output_attentions=True`. Falling back to "
+ 'eager attention. This warning can be removed using the argument `attn_implementation="eager"` when loading the model.'
+ )
+ else:
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.attention_dropout,
+ scaling=self.scaling,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ return attn_output, attn_weights
+
+
+class DummyDecoderLayer(nn.Module):
+ def __init__(self, config: DummyConfig, layer_idx: int):
+ super().__init__()
+ self.hidden_size = config.hidden_size
+
+ self.self_attn = DummyAttention(config=config, layer_idx=layer_idx)
+
+ self.mlp = DummyMLP(config)
+ self.input_layernorm = DummyRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.post_attention_layernorm = DummyRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_value: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = False,
+ cache_position: Optional[torch.LongTensor] = None,
+ position_embeddings: Optional[Tuple[torch.Tensor, torch.Tensor]] = None, # necessary, but kept here for BC
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> Tuple[torch.FloatTensor, Optional[Tuple[torch.FloatTensor, torch.FloatTensor]]]:
+ residual = hidden_states
+
+ hidden_states = self.input_layernorm(hidden_states)
+
+ # Self Attention
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_value=past_key_value,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ position_embeddings=position_embeddings,
+ **kwargs,
+ )
+ hidden_states = residual + hidden_states
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.post_attention_layernorm(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+ if output_attentions:
+ outputs += (self_attn_weights,)
+
+ return outputs
+
+
+DUMMY_START_DOCSTRING = r"""
+ This model inherits from [`PreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) subclass.
+ Use it as a regular PyTorch Module and refer to the PyTorch documentation for all matter related to general usage
+ and behavior.
+
+ Parameters:
+ config ([`DummyConfig`]):
+ Model configuration class with all the parameters of the model. Initializing with a config file does not
+ load the weights associated with the model, only the configuration. Check out the
+ [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+
+@add_start_docstrings(
+ "The bare Dummy Model outputting raw hidden-states without any specific head on top.",
+ DUMMY_START_DOCSTRING,
+)
+class DummyPreTrainedModel(PreTrainedModel):
+ config_class = DummyConfig
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["DummyDecoderLayer"]
+ _skip_keys_device_placement = ["past_key_values"]
+ _supports_flash_attn_2 = True
+ _supports_sdpa = True
+ _supports_cache_class = True
+ _supports_quantized_cache = True
+ _supports_static_cache = True
+
+ def _init_weights(self, module):
+ std = self.config.initializer_range
+ if isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+
+
+DUMMY_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you provide
+ it.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ If `past_key_values` is used, optionally only the last `input_ids` have to be input (see
+ `past_key_values`).
+
+ If you want to change padding behavior, you should read [`modeling_opt._prepare_decoder_attention_mask`]
+ and modify to your needs. See diagram 1 in [the paper](https://arxiv.org/abs/1910.13461) for more
+ information on the default strategy.
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ position_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.n_positions - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ past_key_values (`Cache` or `tuple(tuple(torch.FloatTensor))`, *optional*):
+ Pre-computed hidden-states (key and values in the self-attention blocks and in the cross-attention
+ blocks) that can be used to speed up sequential decoding. This typically consists in the `past_key_values`
+ returned by the model at a previous stage of decoding, when `use_cache=True` or `config.use_cache=True`.
+
+ Two formats are allowed:
+ - a [`~cache_utils.Cache`] instance, see our
+ [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache);
+ - Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of
+ shape `(batch_size, num_heads, sequence_length, embed_size_per_head)`). This is also known as the legacy
+ cache format.
+
+ The model will output the same cache format that is fed as input. If no `past_key_values` are passed, the
+ legacy cache format will be returned.
+
+ If `past_key_values` are used, the user can optionally input only the last `input_ids` (those that don't
+ have their past key value states given to this model) of shape `(batch_size, 1)` instead of all `input_ids`
+ of shape `(batch_size, sequence_length)`.
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see
+ `past_key_values`).
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*):
+ Indices depicting the position of the input sequence tokens in the sequence. Contrarily to `position_ids`,
+ this tensor is not affected by padding. It is used to update the cache in the correct position and to infer
+ the complete sequence length.
+"""
+
+
+@add_start_docstrings(
+ "The bare Dummy Model outputting raw hidden-states without any specific head on top.",
+ DUMMY_START_DOCSTRING,
+)
+class DummyModel(DummyPreTrainedModel):
+ """
+ Transformer decoder consisting of *config.num_hidden_layers* layers. Each layer is a [`DummyDecoderLayer`]
+
+ Args:
+ config: DummyConfig
+ """
+
+ def __init__(self, config: DummyConfig):
+ super().__init__(config)
+ self.padding_idx = config.pad_token_id
+ self.vocab_size = config.vocab_size
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx)
+ self.layers = nn.ModuleList(
+ [DummyDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)]
+ )
+ self.norm = DummyRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.rotary_emb = DummyRotaryEmbedding(config=config)
+ self.gradient_checkpointing = False
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embed_tokens
+
+ def set_input_embeddings(self, value):
+ self.embed_tokens = value
+
+ @add_start_docstrings_to_model_forward(DUMMY_INPUTS_DOCSTRING)
+ def forward(
+ self,
+ input_ids: torch.LongTensor = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **flash_attn_kwargs: Unpack[FlashAttentionKwargs],
+ ) -> Union[Tuple, BaseModelOutputWithPast]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError("You must specify exactly one of input_ids or inputs_embeds")
+
+ if self.gradient_checkpointing and self.training and use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`."
+ )
+ use_cache = False
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ if use_cache and past_key_values is None:
+ past_key_values = DynamicCache()
+
+ if cache_position is None:
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ cache_position = torch.arange(
+ past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device
+ )
+
+ if position_ids is None:
+ position_ids = cache_position.unsqueeze(0)
+
+ causal_mask = self._update_causal_mask(
+ attention_mask, inputs_embeds, cache_position, past_key_values, output_attentions
+ )
+
+ hidden_states = inputs_embeds
+
+ # create position embeddings to be shared across the decoder layers
+ position_embeddings = self.rotary_emb(hidden_states, position_ids)
+
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+
+ for decoder_layer in self.layers[: self.config.num_hidden_layers]:
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ if self.gradient_checkpointing and self.training:
+ layer_outputs = self._gradient_checkpointing_func(
+ decoder_layer.__call__,
+ hidden_states,
+ causal_mask,
+ position_ids,
+ past_key_values,
+ output_attentions,
+ use_cache,
+ cache_position,
+ position_embeddings,
+ )
+ else:
+ layer_outputs = decoder_layer(
+ hidden_states,
+ attention_mask=causal_mask,
+ position_ids=position_ids,
+ past_key_value=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ position_embeddings=position_embeddings,
+ **flash_attn_kwargs,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attns += (layer_outputs[1],)
+
+ hidden_states = self.norm(hidden_states)
+
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ output = BaseModelOutputWithPast(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values if use_cache else None,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ )
+ return output if return_dict else output.to_tuple()
+
+ def _update_causal_mask(
+ self,
+ attention_mask: torch.Tensor,
+ input_tensor: torch.Tensor,
+ cache_position: torch.Tensor,
+ past_key_values: Cache,
+ output_attentions: bool,
+ ):
+ if self.config._attn_implementation == "flash_attention_2":
+ if attention_mask is not None and (attention_mask == 0.0).any():
+ return attention_mask
+ return None
+
+ # For SDPA, when possible, we will rely on its `is_causal` argument instead of its `attn_mask` argument, in
+ # order to dispatch on Flash Attention 2. This feature is not compatible with static cache, as SDPA will fail
+ # to infer the attention mask.
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ using_static_cache = isinstance(past_key_values, StaticCache)
+
+ # When output attentions is True, sdpa implementation's forward method calls the eager implementation's forward
+ if self.config._attn_implementation == "sdpa" and not using_static_cache and not output_attentions:
+ if AttentionMaskConverter._ignore_causal_mask_sdpa(
+ attention_mask,
+ inputs_embeds=input_tensor,
+ past_key_values_length=past_seen_tokens,
+ is_training=self.training,
+ ):
+ return None
+
+ dtype, device = input_tensor.dtype, input_tensor.device
+ sequence_length = input_tensor.shape[1]
+ if using_static_cache:
+ target_length = past_key_values.get_max_cache_shape()
+ else:
+ target_length = (
+ attention_mask.shape[-1]
+ if isinstance(attention_mask, torch.Tensor)
+ else past_seen_tokens + sequence_length + 1
+ )
+
+ # In case the provided `attention` mask is 2D, we generate a causal mask here (4D).
+ causal_mask = self._prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask,
+ sequence_length=sequence_length,
+ target_length=target_length,
+ dtype=dtype,
+ device=device,
+ cache_position=cache_position,
+ batch_size=input_tensor.shape[0],
+ )
+
+ if (
+ self.config._attn_implementation == "sdpa"
+ and attention_mask is not None
+ and attention_mask.device.type == "cuda"
+ and not output_attentions
+ ):
+ # Attend to all tokens in fully masked rows in the causal_mask, for example the relevant first rows when
+ # using left padding. This is required by F.scaled_dot_product_attention memory-efficient attention path.
+ # Details: https://github.com/pytorch/pytorch/issues/110213
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = AttentionMaskConverter._unmask_unattended(causal_mask, min_dtype)
+
+ return causal_mask
+
+ @staticmethod
+ def _prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask: torch.Tensor,
+ sequence_length: int,
+ target_length: int,
+ dtype: torch.dtype,
+ device: torch.device,
+ cache_position: torch.Tensor,
+ batch_size: int,
+ **kwargs,
+ ):
+ """
+ Creates a causal 4D mask of shape `(batch_size, 1, query_length, key_value_length)` from a 2D mask of shape
+ `(batch_size, key_value_length)`, or if the input `attention_mask` is already 4D, do nothing.
+
+ Args:
+ attention_mask (`torch.Tensor`):
+ A 2D attention mask of shape `(batch_size, key_value_length)` or a 4D attention mask of shape
+ `(batch_size, 1, query_length, key_value_length)`.
+ sequence_length (`int`):
+ The sequence length being processed.
+ target_length (`int`):
+ The target length: when generating with static cache, the mask should be as long as the static cache,
+ to account for the 0 padding, the part of the cache that is not filled yet.
+ dtype (`torch.dtype`):
+ The dtype to use for the 4D attention mask.
+ device (`torch.device`):
+ The device to plcae the 4D attention mask on.
+ cache_position (`torch.Tensor`):
+ Indices depicting the position of the input sequence tokens in the sequence.
+ batch_size (`torch.Tensor`):
+ Batch size.
+ """
+ if attention_mask is not None and attention_mask.dim() == 4:
+ # In this case we assume that the mask comes already in inverted form and requires no inversion or slicing.
+ causal_mask = attention_mask
+ else:
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = torch.full(
+ (sequence_length, target_length), fill_value=min_dtype, dtype=dtype, device=device
+ )
+ if sequence_length != 1:
+ causal_mask = torch.triu(causal_mask, diagonal=1)
+ causal_mask *= torch.arange(target_length, device=device) > cache_position.reshape(-1, 1)
+ causal_mask = causal_mask[None, None, :, :].expand(batch_size, 1, -1, -1)
+ if attention_mask is not None:
+ causal_mask = causal_mask.clone() # copy to contiguous memory for in-place edit
+ mask_length = attention_mask.shape[-1]
+ padding_mask = causal_mask[:, :, :, :mask_length] + attention_mask[:, None, None, :]
+ padding_mask = padding_mask == 0
+ causal_mask[:, :, :, :mask_length] = causal_mask[:, :, :, :mask_length].masked_fill(
+ padding_mask, min_dtype
+ )
+
+ return causal_mask
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_dummy_bert.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_dummy_bert.py
new file mode 100644
index 0000000000000000000000000000000000000000..e18e6a19e8a3fabb818a169a132524214bc5b1a1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_dummy_bert.py
@@ -0,0 +1,1011 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from examples/modular-transformers/modular_dummy_bert.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_dummy_bert.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+import math
+import os
+from typing import List, Optional, Tuple, Union
+
+import torch
+from packaging import version
+from torch import nn
+
+from ...activations import ACT2FN
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask_for_sdpa, _prepare_4d_causal_attention_mask_for_sdpa
+from ...modeling_outputs import BaseModelOutputWithPastAndCrossAttentions, BaseModelOutputWithPoolingAndCrossAttentions
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import apply_chunking_to_forward, find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import (
+ add_code_sample_docstrings,
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ get_torch_version,
+ logging,
+)
+from .configuration_dummy_bert import DummyBertConfig
+
+
+logger = logging.get_logger(__name__)
+
+_CHECKPOINT_FOR_DOC = "google-dummy_bert/dummy_bert-base-uncased"
+_CONFIG_FOR_DOC = "DummyBertConfig"
+
+
+class DummyBertEmbeddings(nn.Module):
+ """Construct the embeddings from word, position and token_type embeddings."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id)
+ self.position_embeddings = nn.Embedding(config.max_position_embeddings, config.hidden_size)
+ self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.hidden_size)
+
+ # self.LayerNorm is not snake-cased to stick with TensorFlow model variable name and be able to load
+ # any TensorFlow checkpoint file
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ # position_ids (1, len position emb) is contiguous in memory and exported when serialized
+ self.position_embedding_type = getattr(config, "position_embedding_type", "absolute")
+ self.register_buffer(
+ "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False
+ )
+ self.register_buffer(
+ "token_type_ids", torch.zeros(self.position_ids.size(), dtype=torch.long), persistent=False
+ )
+
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ past_key_values_length: int = 0,
+ ) -> torch.Tensor:
+ if input_ids is not None:
+ input_shape = input_ids.size()
+ else:
+ input_shape = inputs_embeds.size()[:-1]
+
+ seq_length = input_shape[1]
+
+ if position_ids is None:
+ position_ids = self.position_ids[:, past_key_values_length : seq_length + past_key_values_length]
+
+ # Setting the token_type_ids to the registered buffer in constructor where it is all zeros, which usually occurs
+ # when its auto-generated, registered buffer helps users when tracing the model without passing token_type_ids, solves
+ # issue #5664
+ if token_type_ids is None:
+ if hasattr(self, "token_type_ids"):
+ buffered_token_type_ids = self.token_type_ids[:, :seq_length]
+ buffered_token_type_ids_expanded = buffered_token_type_ids.expand(input_shape[0], seq_length)
+ token_type_ids = buffered_token_type_ids_expanded
+ else:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device)
+
+ if inputs_embeds is None:
+ inputs_embeds = self.word_embeddings(input_ids)
+ token_type_embeddings = self.token_type_embeddings(token_type_ids)
+
+ embeddings = inputs_embeds + token_type_embeddings
+ if self.position_embedding_type == "absolute":
+ position_embeddings = self.position_embeddings(position_ids)
+ embeddings += position_embeddings
+ embeddings = self.LayerNorm(embeddings)
+ embeddings = self.dropout(embeddings)
+ return embeddings
+
+
+class DummyBertSelfAttention(nn.Module):
+ def __init__(self, config, position_embedding_type=None):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention "
+ f"heads ({config.num_attention_heads})"
+ )
+
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size)
+
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+ self.position_embedding_type = position_embedding_type or getattr(
+ config, "position_embedding_type", "absolute"
+ )
+ if self.position_embedding_type == "relative_key" or self.position_embedding_type == "relative_key_query":
+ self.max_position_embeddings = config.max_position_embeddings
+ self.distance_embedding = nn.Embedding(2 * config.max_position_embeddings - 1, self.attention_head_size)
+
+ self.is_decoder = config.is_decoder
+
+ def transpose_for_scores(self, x: torch.Tensor) -> torch.Tensor:
+ new_x_shape = x.size()[:-1] + (self.num_attention_heads, self.attention_head_size)
+ x = x.view(new_x_shape)
+ return x.permute(0, 2, 1, 3)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ past_key_value: Optional[Tuple[Tuple[torch.FloatTensor]]] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.Tensor]:
+ mixed_query_layer = self.query(hidden_states)
+
+ # If this is instantiated as a cross-attention module, the keys
+ # and values come from an encoder; the attention mask needs to be
+ # such that the encoder's padding tokens are not attended to.
+ is_cross_attention = encoder_hidden_states is not None
+
+ if is_cross_attention and past_key_value is not None:
+ # reuse k,v, cross_attentions
+ key_layer = past_key_value[0]
+ value_layer = past_key_value[1]
+ attention_mask = encoder_attention_mask
+ elif is_cross_attention:
+ key_layer = self.transpose_for_scores(self.key(encoder_hidden_states))
+ value_layer = self.transpose_for_scores(self.value(encoder_hidden_states))
+ attention_mask = encoder_attention_mask
+ elif past_key_value is not None:
+ key_layer = self.transpose_for_scores(self.key(hidden_states))
+ value_layer = self.transpose_for_scores(self.value(hidden_states))
+ key_layer = torch.cat([past_key_value[0], key_layer], dim=2)
+ value_layer = torch.cat([past_key_value[1], value_layer], dim=2)
+ else:
+ key_layer = self.transpose_for_scores(self.key(hidden_states))
+ value_layer = self.transpose_for_scores(self.value(hidden_states))
+
+ query_layer = self.transpose_for_scores(mixed_query_layer)
+
+ use_cache = past_key_value is not None
+ if self.is_decoder:
+ # if cross_attention save Tuple(torch.Tensor, torch.Tensor) of all cross attention key/value_states.
+ # Further calls to cross_attention layer can then reuse all cross-attention
+ # key/value_states (first "if" case)
+ # if uni-directional self-attention (decoder) save Tuple(torch.Tensor, torch.Tensor) of
+ # all previous decoder key/value_states. Further calls to uni-directional self-attention
+ # can concat previous decoder key/value_states to current projected key/value_states (third "elif" case)
+ # if encoder bi-directional self-attention `past_key_value` is always `None`
+ past_key_value = (key_layer, value_layer)
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2))
+
+ if self.position_embedding_type == "relative_key" or self.position_embedding_type == "relative_key_query":
+ query_length, key_length = query_layer.shape[2], key_layer.shape[2]
+ if use_cache:
+ position_ids_l = torch.tensor(key_length - 1, dtype=torch.long, device=hidden_states.device).view(
+ -1, 1
+ )
+ else:
+ position_ids_l = torch.arange(query_length, dtype=torch.long, device=hidden_states.device).view(-1, 1)
+ position_ids_r = torch.arange(key_length, dtype=torch.long, device=hidden_states.device).view(1, -1)
+ distance = position_ids_l - position_ids_r
+
+ positional_embedding = self.distance_embedding(distance + self.max_position_embeddings - 1)
+ positional_embedding = positional_embedding.to(dtype=query_layer.dtype) # fp16 compatibility
+
+ if self.position_embedding_type == "relative_key":
+ relative_position_scores = torch.einsum("bhld,lrd->bhlr", query_layer, positional_embedding)
+ attention_scores = attention_scores + relative_position_scores
+ elif self.position_embedding_type == "relative_key_query":
+ relative_position_scores_query = torch.einsum("bhld,lrd->bhlr", query_layer, positional_embedding)
+ relative_position_scores_key = torch.einsum("bhrd,lrd->bhlr", key_layer, positional_embedding)
+ attention_scores = attention_scores + relative_position_scores_query + relative_position_scores_key
+
+ attention_scores = attention_scores / math.sqrt(self.attention_head_size)
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in DummyBertModel forward() function)
+ attention_scores = attention_scores + attention_mask
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = nn.functional.softmax(attention_scores, dim=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(attention_probs)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = attention_probs * head_mask
+
+ context_layer = torch.matmul(attention_probs, value_layer)
+
+ context_layer = context_layer.permute(0, 2, 1, 3).contiguous()
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.view(new_context_layer_shape)
+
+ outputs = (context_layer, attention_probs) if output_attentions else (context_layer,)
+
+ if self.is_decoder:
+ outputs = outputs + (past_key_value,)
+ return outputs
+
+
+class DummyBertSdpaSelfAttention(DummyBertSelfAttention):
+ def __init__(self, config, position_embedding_type=None):
+ super().__init__(config, position_embedding_type=position_embedding_type)
+ self.dropout_prob = config.attention_probs_dropout_prob
+ self.require_contiguous_qkv = version.parse(get_torch_version()) < version.parse("2.2.0")
+
+ # Adapted from DummyBertSelfAttention
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ past_key_value: Optional[Tuple[Tuple[torch.FloatTensor]]] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.Tensor]:
+ if self.position_embedding_type != "absolute" or output_attentions or head_mask is not None:
+ # TODO: Improve this warning with e.g. `model.config._attn_implementation = "manual"` once implemented.
+ logger.warning_once(
+ "DummyBertSdpaSelfAttention is used but `torch.nn.functional.scaled_dot_product_attention` does not support "
+ "non-absolute `position_embedding_type` or `output_attentions=True` or `head_mask`. Falling back to "
+ "the manual attention implementation, but specifying the manual implementation will be required from "
+ "Transformers version v5.0.0 onwards. This warning can be removed using the argument "
+ '`attn_implementation="eager"` when loading the model.'
+ )
+ return super().forward(
+ hidden_states,
+ attention_mask,
+ head_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ past_key_value,
+ output_attentions,
+ )
+
+ bsz, tgt_len, _ = hidden_states.size()
+
+ query_layer = self.transpose_for_scores(self.query(hidden_states))
+
+ # If this is instantiated as a cross-attention module, the keys and values come from an encoder; the attention
+ # mask needs to be such that the encoder's padding tokens are not attended to.
+ is_cross_attention = encoder_hidden_states is not None
+
+ current_states = encoder_hidden_states if is_cross_attention else hidden_states
+ attention_mask = encoder_attention_mask if is_cross_attention else attention_mask
+
+ # Check `seq_length` of `past_key_value` == `len(current_states)` to support prefix tuning
+ if is_cross_attention and past_key_value and past_key_value[0].shape[2] == current_states.shape[1]:
+ key_layer, value_layer = past_key_value
+ else:
+ key_layer = self.transpose_for_scores(self.key(current_states))
+ value_layer = self.transpose_for_scores(self.value(current_states))
+ if past_key_value is not None and not is_cross_attention:
+ key_layer = torch.cat([past_key_value[0], key_layer], dim=2)
+ value_layer = torch.cat([past_key_value[1], value_layer], dim=2)
+
+ if self.is_decoder:
+ # if cross_attention save Tuple(torch.Tensor, torch.Tensor) of all cross attention key/value_states.
+ # Further calls to cross_attention layer can then reuse all cross-attention
+ # key/value_states (first "if" case)
+ # if uni-directional self-attention (decoder) save Tuple(torch.Tensor, torch.Tensor) of
+ # all previous decoder key/value_states. Further calls to uni-directional self-attention
+ # can concat previous decoder key/value_states to current projected key/value_states (third "elif" case)
+ # if encoder bi-directional self-attention `past_key_value` is always `None`
+ past_key_value = (key_layer, value_layer)
+
+ # SDPA with memory-efficient backend is broken in torch==2.1.2 when using non-contiguous inputs and a custom
+ # attn_mask, so we need to call `.contiguous()` here. This was fixed in torch==2.2.0.
+ # Reference: https://github.com/pytorch/pytorch/issues/112577
+ if self.require_contiguous_qkv and query_layer.device.type == "cuda" and attention_mask is not None:
+ query_layer = query_layer.contiguous()
+ key_layer = key_layer.contiguous()
+ value_layer = value_layer.contiguous()
+
+ # We dispatch to SDPA's Flash Attention or Efficient kernels via this `is_causal` if statement instead of an inline conditional assignment
+ # in SDPA to support both torch.compile's dynamic shapes and full graph options. An inline conditional prevents dynamic shapes from compiling.
+ # The tgt_len > 1 is necessary to match with AttentionMaskConverter.to_causal_4d that does not create
+ # a causal mask in case tgt_len == 1.
+ is_causal = (
+ True if self.is_decoder and not is_cross_attention and attention_mask is None and tgt_len > 1 else False
+ )
+
+ attn_output = torch.nn.functional.scaled_dot_product_attention(
+ query_layer,
+ key_layer,
+ value_layer,
+ attn_mask=attention_mask,
+ dropout_p=self.dropout_prob if self.training else 0.0,
+ is_causal=is_causal,
+ )
+
+ attn_output = attn_output.transpose(1, 2)
+ attn_output = attn_output.reshape(bsz, tgt_len, self.all_head_size)
+
+ outputs = (attn_output,)
+ if self.is_decoder:
+ outputs = outputs + (past_key_value,)
+ return outputs
+
+
+class DummyBertSelfOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states + input_tensor)
+ return hidden_states
+
+
+DUMMY_BERT_SELF_ATTENTION_CLASSES = {
+ "eager": DummyBertSelfAttention,
+ "sdpa": DummyBertSdpaSelfAttention,
+}
+
+
+class DummyBertAttention(nn.Module):
+ def __init__(self, config, position_embedding_type=None):
+ super().__init__()
+ self.self = DUMMY_BERT_SELF_ATTENTION_CLASSES[config._attn_implementation](
+ config, position_embedding_type=position_embedding_type
+ )
+ self.output = DummyBertSelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.self.num_attention_heads, self.self.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.self.query = prune_linear_layer(self.self.query, index)
+ self.self.key = prune_linear_layer(self.self.key, index)
+ self.self.value = prune_linear_layer(self.self.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.self.num_attention_heads = self.self.num_attention_heads - len(heads)
+ self.self.all_head_size = self.self.attention_head_size * self.self.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ past_key_value: Optional[Tuple[Tuple[torch.FloatTensor]]] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.Tensor]:
+ self_outputs = self.self(
+ hidden_states,
+ attention_mask,
+ head_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ past_key_value,
+ output_attentions,
+ )
+ attention_output = self.output(self_outputs[0], hidden_states)
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+
+class DummyBertIntermediate(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+class DummyBertOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states + input_tensor)
+ return hidden_states
+
+
+class DummyBertLayer(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = DummyBertAttention(config)
+ self.is_decoder = config.is_decoder
+ self.add_cross_attention = config.add_cross_attention
+ if self.add_cross_attention:
+ if not self.is_decoder:
+ raise ValueError(f"{self} should be used as a decoder model if cross attention is added")
+ self.crossattention = DummyBertAttention(config, position_embedding_type="absolute")
+ self.intermediate = DummyBertIntermediate(config)
+ self.output = DummyBertOutput(config)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ past_key_value: Optional[Tuple[Tuple[torch.FloatTensor]]] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.Tensor]:
+ # decoder uni-directional self-attention cached key/values tuple is at positions 1,2
+ self_attn_past_key_value = past_key_value[:2] if past_key_value is not None else None
+ self_attention_outputs = self.attention(
+ hidden_states,
+ attention_mask,
+ head_mask,
+ output_attentions=output_attentions,
+ past_key_value=self_attn_past_key_value,
+ )
+ attention_output = self_attention_outputs[0]
+
+ # if decoder, the last output is tuple of self-attn cache
+ if self.is_decoder:
+ outputs = self_attention_outputs[1:-1]
+ present_key_value = self_attention_outputs[-1]
+ else:
+ outputs = self_attention_outputs[1:] # add self attentions if we output attention weights
+
+ cross_attn_present_key_value = None
+ if self.is_decoder and encoder_hidden_states is not None:
+ if not hasattr(self, "crossattention"):
+ raise ValueError(
+ f"If `encoder_hidden_states` are passed, {self} has to be instantiated with cross-attention layers"
+ " by setting `config.add_cross_attention=True`"
+ )
+
+ # cross_attn cached key/values tuple is at positions 3,4 of past_key_value tuple
+ cross_attn_past_key_value = past_key_value[-2:] if past_key_value is not None else None
+ cross_attention_outputs = self.crossattention(
+ attention_output,
+ attention_mask,
+ head_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ cross_attn_past_key_value,
+ output_attentions,
+ )
+ attention_output = cross_attention_outputs[0]
+ outputs = outputs + cross_attention_outputs[1:-1] # add cross attentions if we output attention weights
+
+ # add cross-attn cache to positions 3,4 of present_key_value tuple
+ cross_attn_present_key_value = cross_attention_outputs[-1]
+ present_key_value = present_key_value + cross_attn_present_key_value
+
+ layer_output = apply_chunking_to_forward(
+ self.feed_forward_chunk, self.chunk_size_feed_forward, self.seq_len_dim, attention_output
+ )
+ outputs = (layer_output,) + outputs
+
+ # if decoder, return the attn key/values as the last output
+ if self.is_decoder:
+ outputs = outputs + (present_key_value,)
+
+ return outputs
+
+ def feed_forward_chunk(self, attention_output):
+ intermediate_output = self.intermediate(attention_output)
+ layer_output = self.output(intermediate_output, attention_output)
+ return layer_output
+
+
+class DummyBertEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([DummyBertLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ past_key_values: Optional[Tuple[Tuple[torch.FloatTensor]]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = False,
+ output_hidden_states: Optional[bool] = False,
+ return_dict: Optional[bool] = True,
+ ) -> Union[Tuple[torch.Tensor], BaseModelOutputWithPastAndCrossAttentions]:
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+ all_cross_attentions = () if output_attentions and self.config.add_cross_attention else None
+
+ if self.gradient_checkpointing and self.training:
+ if use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..."
+ )
+ use_cache = False
+
+ next_decoder_cache = () if use_cache else None
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+ past_key_value = past_key_values[i] if past_key_values is not None else None
+
+ if self.gradient_checkpointing and self.training:
+ layer_outputs = self._gradient_checkpointing_func(
+ layer_module.__call__,
+ hidden_states,
+ attention_mask,
+ layer_head_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ past_key_value,
+ output_attentions,
+ )
+ else:
+ layer_outputs = layer_module(
+ hidden_states,
+ attention_mask,
+ layer_head_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ past_key_value,
+ output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+ if use_cache:
+ next_decoder_cache += (layer_outputs[-1],)
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+ if self.config.add_cross_attention:
+ all_cross_attentions = all_cross_attentions + (layer_outputs[2],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [
+ hidden_states,
+ next_decoder_cache,
+ all_hidden_states,
+ all_self_attentions,
+ all_cross_attentions,
+ ]
+ if v is not None
+ )
+ return BaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=next_decoder_cache,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ cross_attentions=all_cross_attentions,
+ )
+
+
+class DummyBertPooler(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.activation = nn.Tanh()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(first_token_tensor)
+ pooled_output = self.activation(pooled_output)
+ return pooled_output
+
+
+def load_tf_weights_in_dummy_bert(model, config, tf_checkpoint_path):
+ """Load tf checkpoints in a pytorch model."""
+ try:
+ import re
+
+ import numpy as np
+ import tensorflow as tf
+ except ImportError:
+ logger.error(
+ "Loading a TensorFlow model in PyTorch, requires TensorFlow to be installed. Please see "
+ "https://www.tensorflow.org/install/ for installation instructions."
+ )
+ raise
+ tf_path = os.path.abspath(tf_checkpoint_path)
+ logger.info(f"Converting TensorFlow checkpoint from {tf_path}")
+ # Load weights from TF model
+ init_vars = tf.train.list_variables(tf_path)
+ names = []
+ arrays = []
+ for name, shape in init_vars:
+ logger.info(f"Loading TF weight {name} with shape {shape}")
+ array = tf.train.load_variable(tf_path, name)
+ names.append(name)
+ arrays.append(array)
+
+ for name, array in zip(names, arrays):
+ name = name.split("/")
+ # adam_v and adam_m are variables used in AdamWeightDecayOptimizer to calculated m and v
+ # which are not required for using pretrained model
+ if any(
+ n in ["adam_v", "adam_m", "AdamWeightDecayOptimizer", "AdamWeightDecayOptimizer_1", "global_step"]
+ for n in name
+ ):
+ logger.info(f"Skipping {'/'.join(name)}")
+ continue
+ pointer = model
+ for m_name in name:
+ if re.fullmatch(r"[A-Za-z]+_\d+", m_name):
+ scope_names = re.split(r"_(\d+)", m_name)
+ else:
+ scope_names = [m_name]
+ if scope_names[0] == "kernel" or scope_names[0] == "gamma":
+ pointer = getattr(pointer, "weight")
+ elif scope_names[0] == "output_bias" or scope_names[0] == "beta":
+ pointer = getattr(pointer, "bias")
+ elif scope_names[0] == "output_weights":
+ pointer = getattr(pointer, "weight")
+ elif scope_names[0] == "squad":
+ pointer = getattr(pointer, "classifier")
+ else:
+ try:
+ pointer = getattr(pointer, scope_names[0])
+ except AttributeError:
+ logger.info(f"Skipping {'/'.join(name)}")
+ continue
+ if len(scope_names) >= 2:
+ num = int(scope_names[1])
+ pointer = pointer[num]
+ if m_name[-11:] == "_embeddings":
+ pointer = getattr(pointer, "weight")
+ elif m_name == "kernel":
+ array = np.transpose(array)
+ try:
+ if pointer.shape != array.shape:
+ raise ValueError(f"Pointer shape {pointer.shape} and array shape {array.shape} mismatched")
+ except ValueError as e:
+ e.args += (pointer.shape, array.shape)
+ raise
+ logger.info(f"Initialize PyTorch weight {name}")
+ pointer.data = torch.from_numpy(array)
+ return model
+
+
+class DummyBertPreTrainedModel(PreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = DummyBertConfig
+ load_tf_weights = load_tf_weights_in_dummy_bert
+ base_model_prefix = "dummy_bert"
+ supports_gradient_checkpointing = True
+ _supports_sdpa = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, nn.Linear):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+
+
+DUMMY_BERT_START_DOCSTRING = r"""
+
+ This model inherits from [`PreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) subclass.
+ Use it as a regular PyTorch Module and refer to the PyTorch documentation for all matter related to general usage
+ and behavior.
+
+ Parameters:
+ config ([`DummyBertConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+DUMMY_BERT_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`torch.LongTensor` of shape `({0})`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`torch.FloatTensor` of shape `({0})`or `(batch_size, sequence_length, target_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ token_type_ids (`torch.LongTensor` of shape `({0})`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`torch.LongTensor` of shape `({0})`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ head_mask (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ inputs_embeds (`torch.FloatTensor` of shape `({0}, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+
+@add_start_docstrings(
+ "The bare DummyBert Model transformer outputting raw hidden-states without any specific head on top.",
+ DUMMY_BERT_START_DOCSTRING,
+)
+class DummyBertModel(DummyBertPreTrainedModel):
+ """
+
+ The model can behave as an encoder (with only self-attention) as well as a decoder, in which case a layer of
+ cross-attention is added between the self-attention layers, following the architecture described in [Attention is
+ all you need](https://arxiv.org/abs/1706.03762) by Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit,
+ Llion Jones, Aidan N. Gomez, Lukasz Kaiser and Illia Polosukhin.
+
+ To behave as an decoder the model needs to be initialized with the `is_decoder` argument of the configuration set
+ to `True`. To be used in a Seq2Seq model, the model needs to initialized with both `is_decoder` argument and
+ `add_cross_attention` set to `True`; an `encoder_hidden_states` is then expected as an input to the forward pass.
+ """
+
+ _no_split_modules = ["DummyBertEmbeddings", "DummyBertLayer"]
+
+ def __init__(self, config, add_pooling_layer=True):
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = DummyBertEmbeddings(config)
+ self.encoder = DummyBertEncoder(config)
+
+ self.pooler = DummyBertPooler(config) if add_pooling_layer else None
+
+ self.attn_implementation = config._attn_implementation
+ self.position_embedding_type = config.position_embedding_type
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.word_embeddings
+
+ def set_input_embeddings(self, value):
+ self.embeddings.word_embeddings = value
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @add_start_docstrings_to_model_forward(DUMMY_BERT_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=BaseModelOutputWithPoolingAndCrossAttentions,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[List[torch.FloatTensor]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[Tuple[torch.Tensor], BaseModelOutputWithPoolingAndCrossAttentions]:
+ r"""
+ encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention if
+ the model is configured as a decoder.
+ encoder_attention_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length)` or `(batch_size, sequence_length, target_length)`, *optional*):
+ Mask to avoid performing attention on the padding token indices of the encoder input. This mask is used in
+ the cross-attention if the model is configured as a decoder. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+ past_key_values (`tuple(tuple(torch.FloatTensor))` of length `config.n_layers` with each tuple having 4 tensors of shape `(batch_size, num_heads, sequence_length - 1, embed_size_per_head)`):
+ Contains precomputed key and value hidden states of the attention blocks. Can be used to speed up decoding.
+
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those that
+ don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of all
+ `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see
+ `past_key_values`).
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if self.config.is_decoder:
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ else:
+ use_cache = False
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask)
+ input_shape = input_ids.size()
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ batch_size, seq_length = input_shape
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ # past_key_values_length
+ past_key_values_length = past_key_values[0][0].shape[2] if past_key_values is not None else 0
+
+ if token_type_ids is None:
+ if hasattr(self.embeddings, "token_type_ids"):
+ buffered_token_type_ids = self.embeddings.token_type_ids[:, :seq_length]
+ buffered_token_type_ids_expanded = buffered_token_type_ids.expand(batch_size, seq_length)
+ token_type_ids = buffered_token_type_ids_expanded
+ else:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=device)
+
+ embedding_output = self.embeddings(
+ input_ids=input_ids,
+ position_ids=position_ids,
+ token_type_ids=token_type_ids,
+ inputs_embeds=inputs_embeds,
+ past_key_values_length=past_key_values_length,
+ )
+
+ if attention_mask is None:
+ attention_mask = torch.ones((batch_size, seq_length + past_key_values_length), device=device)
+
+ use_sdpa_attention_masks = (
+ self.attn_implementation == "sdpa"
+ and self.position_embedding_type == "absolute"
+ and head_mask is None
+ and not output_attentions
+ )
+
+ # Expand the attention mask
+ if use_sdpa_attention_masks and attention_mask.dim() == 2:
+ # Expand the attention mask for SDPA.
+ # [bsz, seq_len] -> [bsz, 1, seq_len, seq_len]
+ if self.config.is_decoder:
+ extended_attention_mask = _prepare_4d_causal_attention_mask_for_sdpa(
+ attention_mask,
+ input_shape,
+ embedding_output,
+ past_key_values_length,
+ )
+ else:
+ extended_attention_mask = _prepare_4d_attention_mask_for_sdpa(
+ attention_mask, embedding_output.dtype, tgt_len=seq_length
+ )
+ else:
+ # We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length]
+ # ourselves in which case we just need to make it broadcastable to all heads.
+ extended_attention_mask = self.get_extended_attention_mask(attention_mask, input_shape)
+
+ # If a 2D or 3D attention mask is provided for the cross-attention
+ # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length]
+ if self.config.is_decoder and encoder_hidden_states is not None:
+ encoder_batch_size, encoder_sequence_length, _ = encoder_hidden_states.size()
+ encoder_hidden_shape = (encoder_batch_size, encoder_sequence_length)
+ if encoder_attention_mask is None:
+ encoder_attention_mask = torch.ones(encoder_hidden_shape, device=device)
+
+ if use_sdpa_attention_masks and encoder_attention_mask.dim() == 2:
+ # Expand the attention mask for SDPA.
+ # [bsz, seq_len] -> [bsz, 1, seq_len, seq_len]
+ encoder_extended_attention_mask = _prepare_4d_attention_mask_for_sdpa(
+ encoder_attention_mask, embedding_output.dtype, tgt_len=seq_length
+ )
+ else:
+ encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask)
+ else:
+ encoder_extended_attention_mask = None
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ encoder_outputs = self.encoder(
+ embedding_output,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_extended_attention_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = encoder_outputs[0]
+ pooled_output = self.pooler(sequence_output) if self.pooler is not None else None
+
+ if not return_dict:
+ return (sequence_output, pooled_output) + encoder_outputs[1:]
+
+ return BaseModelOutputWithPoolingAndCrossAttentions(
+ last_hidden_state=sequence_output,
+ pooler_output=pooled_output,
+ past_key_values=encoder_outputs.past_key_values,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ cross_attentions=encoder_outputs.cross_attentions,
+ )
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_from_uppercase_model.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_from_uppercase_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..d6c16c697437d8844c9ce818eac98dbfedd1de5f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_from_uppercase_model.py
@@ -0,0 +1,357 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from examples/modular-transformers/modular_from_uppercase_model.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_from_uppercase_model.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+from typing import Optional, Tuple
+
+import torch
+from torch import nn
+
+from ...activations import ACT2FN
+from ...pytorch_utils import is_torch_greater_or_equal_than_2_2
+from ...utils import is_flash_attn_2_available, is_flash_attn_greater_or_equal_2_10, logging
+from .configuration_from_uppercase_model import FromUppercaseModelConfig
+
+
+if is_flash_attn_2_available():
+ from ...modeling_flash_attention_utils import _flash_attention_forward
+
+
+logger = logging.get_logger(__name__)
+
+
+class FromUppercaseModelAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.embed_dim = config.hidden_size
+ self.num_heads = config.num_attention_heads
+ self.head_dim = self.embed_dim // self.num_heads
+ if self.head_dim * self.num_heads != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`:"
+ f" {self.num_heads})."
+ )
+ self.scale = self.head_dim**-0.5
+ self.dropout = config.attention_dropout
+
+ self.k_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.v_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.q_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.out_proj = nn.Linear(self.embed_dim, self.embed_dim)
+
+ def _shape(self, tensor: torch.Tensor, seq_len: int, bsz: int):
+ return tensor.view(bsz, seq_len, self.num_heads, self.head_dim).transpose(1, 2).contiguous()
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ causal_attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.Tensor, Optional[torch.Tensor]]:
+ """Input shape: Batch x Time x Channel"""
+
+ bsz, tgt_len, embed_dim = hidden_states.size()
+
+ # get query proj
+ query_states = self.q_proj(hidden_states) * self.scale
+ key_states = self._shape(self.k_proj(hidden_states), -1, bsz)
+ value_states = self._shape(self.v_proj(hidden_states), -1, bsz)
+
+ proj_shape = (bsz * self.num_heads, -1, self.head_dim)
+ query_states = self._shape(query_states, tgt_len, bsz).view(*proj_shape)
+ key_states = key_states.view(*proj_shape)
+ value_states = value_states.view(*proj_shape)
+
+ src_len = key_states.size(1)
+ attn_weights = torch.bmm(query_states, key_states.transpose(1, 2))
+
+ if attn_weights.size() != (bsz * self.num_heads, tgt_len, src_len):
+ raise ValueError(
+ f"Attention weights should be of size {(bsz * self.num_heads, tgt_len, src_len)}, but is"
+ f" {attn_weights.size()}"
+ )
+
+ # apply the causal_attention_mask first
+ if causal_attention_mask is not None:
+ if causal_attention_mask.size() != (bsz, 1, tgt_len, src_len):
+ raise ValueError(
+ f"Attention mask should be of size {(bsz, 1, tgt_len, src_len)}, but is"
+ f" {causal_attention_mask.size()}"
+ )
+ attn_weights = attn_weights.view(bsz, self.num_heads, tgt_len, src_len) + causal_attention_mask
+ attn_weights = attn_weights.view(bsz * self.num_heads, tgt_len, src_len)
+
+ if attention_mask is not None:
+ if attention_mask.size() != (bsz, 1, tgt_len, src_len):
+ raise ValueError(
+ f"Attention mask should be of size {(bsz, 1, tgt_len, src_len)}, but is {attention_mask.size()}"
+ )
+ attn_weights = attn_weights.view(bsz, self.num_heads, tgt_len, src_len) + attention_mask
+ attn_weights = attn_weights.view(bsz * self.num_heads, tgt_len, src_len)
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1)
+
+ if output_attentions:
+ # this operation is a bit akward, but it's required to
+ # make sure that attn_weights keeps its gradient.
+ # In order to do so, attn_weights have to reshaped
+ # twice and have to be reused in the following
+ attn_weights_reshaped = attn_weights.view(bsz, self.num_heads, tgt_len, src_len)
+ attn_weights = attn_weights_reshaped.view(bsz * self.num_heads, tgt_len, src_len)
+ else:
+ attn_weights_reshaped = None
+
+ attn_probs = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training)
+
+ attn_output = torch.bmm(attn_probs, value_states)
+
+ if attn_output.size() != (bsz * self.num_heads, tgt_len, self.head_dim):
+ raise ValueError(
+ f"`attn_output` should be of size {(bsz, self.num_heads, tgt_len, self.head_dim)}, but is"
+ f" {attn_output.size()}"
+ )
+
+ attn_output = attn_output.view(bsz, self.num_heads, tgt_len, self.head_dim)
+ attn_output = attn_output.transpose(1, 2)
+ attn_output = attn_output.reshape(bsz, tgt_len, embed_dim)
+
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights_reshaped
+
+
+class FromUppercaseModelFlashAttention2(FromUppercaseModelAttention):
+ """
+ FromUppercaseModelAttention flash attention module. This module inherits from `FromUppercaseModelAttention` as the weights of the module stays
+ untouched. The only required change would be on the forward pass where it needs to correctly call the public API of
+ flash attention and deal with padding tokens in case the input contains any of them.
+ """
+
+ def __init__(self, *args, **kwargs):
+ super().__init__(*args, **kwargs)
+
+ # TODO: Should be removed once Flash Attention for RoCm is bumped to 2.1.
+ # flash_attn<2.1 generates top-left aligned causal mask, while what is needed here is bottom-right alignement, that was made default for flash_attn>=2.1. This attribute is used to handle this difference. Reference: https://github.com/Dao-AILab/flash-attention/releases/tag/v2.1.0.
+ # Beware that with flash_attn<2.1, using q_seqlen != k_seqlen (except for the case q_seqlen == 1) produces a wrong mask (top-left).
+ self._flash_attn_uses_top_left_mask = not is_flash_attn_greater_or_equal_2_10()
+
+ # Adapted from transformers.models.llama.modeling_llama.LlamaFlashAttention2.forward
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ causal_attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.Tensor, Optional[torch.Tensor]]:
+ output_attentions = False
+
+ batch_size, q_len, _ = hidden_states.size()
+
+ query_states = self.q_proj(hidden_states)
+ key_states = self.k_proj(hidden_states)
+ value_states = self.v_proj(hidden_states)
+
+ # Flash attention requires the input to have the shape
+ # batch_size x seq_length x head_dim x hidden_dim
+ # therefore we just need to keep the original shape
+ query_states = query_states.view(batch_size, q_len, self.num_heads, self.head_dim)
+ key_states = key_states.view(batch_size, q_len, self.num_heads, self.head_dim)
+ value_states = value_states.view(batch_size, q_len, self.num_heads, self.head_dim)
+
+ dropout_rate = self.dropout if self.training else 0.0
+
+ # In PEFT, usually we cast the layer norms in float32 for training stability reasons
+ # therefore the input hidden states gets silently casted in float32. Hence, we need
+ # cast them back in the correct dtype just to be sure everything works as expected.
+ # This might slowdown training & inference so it is recommended to not cast the LayerNorms
+ # in fp32.
+
+ input_dtype = query_states.dtype
+ if input_dtype == torch.float32:
+ if torch.is_autocast_enabled():
+ target_dtype = torch.get_autocast_gpu_dtype()
+ # Handle the case where the model is quantized
+ elif hasattr(self.config, "_pre_quantization_dtype"):
+ target_dtype = self.config._pre_quantization_dtype
+ else:
+ target_dtype = self.q_proj.weight.dtype
+
+ logger.warning_once(
+ f"The input hidden states seems to be silently casted in float32, this might be related to"
+ f" the fact you have upcasted embedding or layer norm layers in float32. We will cast back the input in"
+ f" {target_dtype}."
+ )
+
+ query_states = query_states.to(target_dtype)
+ key_states = key_states.to(target_dtype)
+ value_states = value_states.to(target_dtype)
+
+ attn_output = _flash_attention_forward(
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ q_len,
+ dropout=dropout_rate,
+ is_causal=causal_attention_mask is not None,
+ use_top_left_mask=self._flash_attn_uses_top_left_mask,
+ )
+
+ attn_output = attn_output.reshape(batch_size, q_len, self.embed_dim).contiguous()
+ attn_output = self.out_proj(attn_output)
+
+ if not output_attentions:
+ attn_weights = None
+
+ return attn_output, attn_weights
+
+
+class FromUppercaseModelSdpaAttention(FromUppercaseModelAttention):
+ """
+ SDPA attention module using torch.nn.functional.scaled_dot_product_attention. This module inherits from
+ `FromUppercaseModelAttention` as the weights of the module stays untouched. The only changes are on the forward pass to adapt to
+ SDPA API.
+ """
+
+ # Adapted from FromUppercaseModelAttention.forward
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ causal_attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.Tensor, Optional[torch.Tensor]]:
+ if output_attentions:
+ # TODO: Improve this warning with e.g. `model.config.attn_implementation = "manual"` once this is implemented.
+ logger.warning_once(
+ "FromUppercaseModelModel is using FromUppercaseModelSdpaAttention, but `torch.nn.functional.scaled_dot_product_attention` does not "
+ "support `output_attentions=True`. Falling back to the manual attention implementation, but specifying "
+ "the manual implementation will be required from Transformers version v5.0.0 onwards. This warning can "
+ 'be removed using the argument `attn_implementation="eager"` when loading the model.'
+ )
+ return super().forward(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ causal_attention_mask=causal_attention_mask,
+ output_attentions=output_attentions,
+ )
+
+ # FROM_UPPERCASE_MODEL text model uses both `causal_attention_mask` and `attention_mask`
+ if attention_mask is not None and causal_attention_mask is not None:
+ attn_mask = attention_mask + causal_attention_mask
+ elif causal_attention_mask is not None:
+ attn_mask = causal_attention_mask
+ else:
+ attn_mask = attention_mask
+
+ bsz, tgt_len, embed_dim = hidden_states.size()
+
+ query_states = self.q_proj(hidden_states)
+ key_states = self.k_proj(hidden_states)
+ value_states = self.v_proj(hidden_states)
+
+ query_states = query_states.view(bsz, -1, self.num_heads, self.head_dim).transpose(1, 2)
+ key_states = key_states.view(bsz, -1, self.num_heads, self.head_dim).transpose(1, 2)
+ value_states = value_states.view(bsz, -1, self.num_heads, self.head_dim).transpose(1, 2)
+
+ # SDPA with memory-efficient backend is currently (torch==2.1.2) bugged with non-contiguous inputs with custom attn_mask,
+ # Reference: https://github.com/pytorch/pytorch/issues/112577.
+ if not is_torch_greater_or_equal_than_2_2 and query_states.device.type == "cuda" and attn_mask is not None:
+ query_states = query_states.contiguous()
+ key_states = key_states.contiguous()
+ value_states = value_states.contiguous()
+
+ # FROM_UPPERCASE_MODEL text model uses both `causal_attention_mask` and `attention_mask` sequentially.
+ attn_output = torch.nn.functional.scaled_dot_product_attention(
+ query_states,
+ key_states,
+ value_states,
+ attn_mask=attn_mask,
+ dropout_p=self.dropout if self.training else 0.0,
+ scale=self.scale,
+ )
+
+ attn_output = attn_output.transpose(1, 2)
+ attn_output = attn_output.reshape(bsz, tgt_len, embed_dim)
+
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, None
+
+
+class FromUppercaseModelMLP(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.activation_fn = ACT2FN[config.hidden_act]
+ self.fc1 = nn.Linear(config.hidden_size, config.intermediate_size)
+ self.fc2 = nn.Linear(config.intermediate_size, config.hidden_size)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.fc1(hidden_states)
+ hidden_states = self.activation_fn(hidden_states)
+ hidden_states = self.fc2(hidden_states)
+ return hidden_states
+
+
+FROM_UPPERCASE_MODEL_ATTENTION_CLASSES = {
+ "eager": FromUppercaseModelAttention,
+ "sdpa": FromUppercaseModelSdpaAttention,
+ "flash_attention_2": FromUppercaseModelFlashAttention2,
+}
+
+
+class FromUppercaseModelEncoderLayer(nn.Module):
+ def __init__(self, config: FromUppercaseModelConfig):
+ super().__init__()
+ self.embed_dim = config.hidden_size
+ self.self_attn = FROM_UPPERCASE_MODEL_ATTENTION_CLASSES[config._attn_implementation](config)
+ self.layer_norm1 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
+ self.mlp = FromUppercaseModelMLP(config)
+ self.layer_norm2 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: torch.Tensor,
+ causal_attention_mask: torch.Tensor,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.FloatTensor]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ `(config.encoder_attention_heads,)`.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+
+ hidden_states = self.layer_norm1(hidden_states)
+ hidden_states, attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ causal_attention_mask=causal_attention_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.layer_norm2(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_multimodal1.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_multimodal1.py
new file mode 100644
index 0000000000000000000000000000000000000000..df23a83b3411447747170ae2e6fdc52077c0f28e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_multimodal1.py
@@ -0,0 +1,710 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from examples/modular-transformers/modular_multimodal1.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_multimodal1.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+from typing import Callable, Optional, Tuple, Union
+
+import torch
+from torch import nn
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache, StaticCache
+from ...modeling_attn_mask_utils import AttentionMaskConverter
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_outputs import BaseModelOutputWithPast
+from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import add_start_docstrings, add_start_docstrings_to_model_forward, logging
+from .configuration_multimodal1 import Multimodal1TextConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class Multimodal1TextRMSNorm(nn.Module):
+ def __init__(self, hidden_size, eps=1e-6):
+ """
+ Multimodal1TextRMSNorm is equivalent to T5LayerNorm
+ """
+ super().__init__()
+ self.weight = nn.Parameter(torch.ones(hidden_size))
+ self.variance_epsilon = eps
+
+ def forward(self, hidden_states):
+ input_dtype = hidden_states.dtype
+ hidden_states = hidden_states.to(torch.float32)
+ variance = hidden_states.pow(2).mean(-1, keepdim=True)
+ hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon)
+ return self.weight * hidden_states.to(input_dtype)
+
+ def extra_repr(self):
+ return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}"
+
+
+class Multimodal1TextRotaryEmbedding(nn.Module):
+ def __init__(
+ self,
+ config: Multimodal1TextConfig,
+ device=None,
+ ):
+ super().__init__()
+ self.rope_kwargs = {}
+ # BC: "rope_type" was originally "type"
+ if hasattr(config, "rope_scaling") and config.rope_scaling is not None:
+ self.rope_type = config.rope_scaling.get("rope_type", config.rope_scaling.get("type"))
+ else:
+ self.rope_type = "default"
+ self.max_seq_len_cached = config.max_position_embeddings
+ self.original_max_seq_len = config.max_position_embeddings
+
+ self.config = config
+ self.rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type]
+
+ inv_freq, self.attention_scaling = self.rope_init_fn(self.config, device, **self.rope_kwargs)
+ self.register_buffer("inv_freq", inv_freq, persistent=False)
+ self.original_inv_freq = self.inv_freq
+
+ def _dynamic_frequency_update(self, position_ids, device):
+ """
+ dynamic RoPE layers should recompute `inv_freq` in the following situations:
+ 1 - growing beyond the cached sequence length (allow scaling)
+ 2 - the current sequence length is in the original scale (avoid losing precision with small sequences)
+ """
+ seq_len = torch.max(position_ids) + 1
+ if seq_len > self.max_seq_len_cached: # growth
+ inv_freq, self.attention_scaling = self.rope_init_fn(
+ self.config, device, seq_len=seq_len, **self.rope_kwargs
+ )
+ self.register_buffer("inv_freq", inv_freq, persistent=False) # TODO joao: may break with compilation
+ self.max_seq_len_cached = seq_len
+
+ if seq_len < self.original_max_seq_len and self.max_seq_len_cached > self.original_max_seq_len: # reset
+ self.register_buffer("inv_freq", self.original_inv_freq, persistent=False)
+ self.max_seq_len_cached = self.original_max_seq_len
+
+ @torch.no_grad()
+ def forward(self, x, position_ids):
+ if "dynamic" in self.rope_type:
+ self._dynamic_frequency_update(position_ids, device=x.device)
+
+ # Core RoPE block
+ inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1)
+ position_ids_expanded = position_ids[:, None, :].float()
+ # Force float32 (see https://github.com/huggingface/transformers/pull/29285)
+ device_type = x.device.type
+ device_type = device_type if isinstance(device_type, str) and device_type != "mps" else "cpu"
+ with torch.autocast(device_type=device_type, enabled=False):
+ freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2)
+ emb = torch.cat((freqs, freqs), dim=-1)
+ cos = emb.cos()
+ sin = emb.sin()
+
+ # Advanced RoPE types (e.g. yarn) apply a post-processing scaling factor, equivalent to scaling attention
+ cos = cos * self.attention_scaling
+ sin = sin * self.attention_scaling
+
+ return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype)
+
+
+class Multimodal1TextMLP(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.hidden_size = config.hidden_size
+ self.intermediate_size = config.intermediate_size
+ self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=config.mlp_bias)
+ self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=config.mlp_bias)
+ self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=config.mlp_bias)
+ self.act_fn = ACT2FN[config.hidden_act]
+
+ def forward(self, x):
+ down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x))
+ return down_proj
+
+
+def rotate_half(x):
+ """Rotates half the hidden dims of the input."""
+ x1 = x[..., : x.shape[-1] // 2]
+ x2 = x[..., x.shape[-1] // 2 :]
+ return torch.cat((-x2, x1), dim=-1)
+
+
+def apply_rotary_pos_emb(q, k, cos, sin, position_ids=None, unsqueeze_dim=1):
+ """Applies Rotary Position Embedding to the query and key tensors.
+
+ Args:
+ q (`torch.Tensor`): The query tensor.
+ k (`torch.Tensor`): The key tensor.
+ cos (`torch.Tensor`): The cosine part of the rotary embedding.
+ sin (`torch.Tensor`): The sine part of the rotary embedding.
+ position_ids (`torch.Tensor`, *optional*):
+ Deprecated and unused.
+ unsqueeze_dim (`int`, *optional*, defaults to 1):
+ The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and
+ sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note
+ that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and
+ k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes
+ cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have
+ the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2.
+ Returns:
+ `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding.
+ """
+ cos = cos.unsqueeze(unsqueeze_dim)
+ sin = sin.unsqueeze(unsqueeze_dim)
+ q_embed = (q * cos) + (rotate_half(q) * sin)
+ k_embed = (k * cos) + (rotate_half(k) * sin)
+ return q_embed, k_embed
+
+
+def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor:
+ """
+ This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch,
+ num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim)
+ """
+ batch, num_key_value_heads, slen, head_dim = hidden_states.shape
+ if n_rep == 1:
+ return hidden_states
+ hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim)
+ return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim)
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ key_states = repeat_kv(key, module.num_key_value_groups)
+ value_states = repeat_kv(value, module.num_key_value_groups)
+
+ attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling
+ if attention_mask is not None:
+ causal_mask = attention_mask[:, :, :, : key_states.shape[-2]]
+ attn_weights = attn_weights + causal_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value_states)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class Multimodal1TextAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config: Multimodal1TextConfig, layer_idx: int):
+ super().__init__()
+ self.config = config
+ self.layer_idx = layer_idx
+ self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads)
+ self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads
+ self.scaling = self.head_dim**-0.5
+ self.attention_dropout = config.attention_dropout
+ self.is_causal = True
+
+ self.q_proj = nn.Linear(
+ config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.k_proj = nn.Linear(
+ config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.v_proj = nn.Linear(
+ config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.o_proj = nn.Linear(
+ config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_bias
+ )
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ position_embeddings: Tuple[torch.Tensor, torch.Tensor],
+ attention_mask: Optional[torch.Tensor],
+ past_key_value: Optional[Cache] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> Tuple[torch.Tensor, Optional[torch.Tensor], Optional[Tuple[torch.Tensor]]]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+
+ query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ cos, sin = position_embeddings
+ query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin)
+
+ if past_key_value is not None:
+ # sin and cos are specific to RoPE models; cache_position needed for the static cache
+ cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position}
+ key_states, value_states = past_key_value.update(key_states, value_states, self.layer_idx, cache_kwargs)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ if self.config._attn_implementation == "sdpa" and kwargs.get("output_attentions", False):
+ logger.warning_once(
+ "`torch.nn.functional.scaled_dot_product_attention` does not support `output_attentions=True`. Falling back to "
+ 'eager attention. This warning can be removed using the argument `attn_implementation="eager"` when loading the model.'
+ )
+ else:
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.attention_dropout,
+ scaling=self.scaling,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ return attn_output, attn_weights
+
+
+class Multimodal1TextDecoderLayer(nn.Module):
+ def __init__(self, config: Multimodal1TextConfig, layer_idx: int):
+ super().__init__()
+ self.hidden_size = config.hidden_size
+
+ self.self_attn = Multimodal1TextAttention(config=config, layer_idx=layer_idx)
+
+ self.mlp = Multimodal1TextMLP(config)
+ self.input_layernorm = Multimodal1TextRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.post_attention_layernorm = Multimodal1TextRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_value: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = False,
+ cache_position: Optional[torch.LongTensor] = None,
+ position_embeddings: Optional[Tuple[torch.Tensor, torch.Tensor]] = None, # necessary, but kept here for BC
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> Tuple[torch.FloatTensor, Optional[Tuple[torch.FloatTensor, torch.FloatTensor]]]:
+ residual = hidden_states
+
+ hidden_states = self.input_layernorm(hidden_states)
+
+ # Self Attention
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_value=past_key_value,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ position_embeddings=position_embeddings,
+ **kwargs,
+ )
+ hidden_states = residual + hidden_states
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.post_attention_layernorm(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+ if output_attentions:
+ outputs += (self_attn_weights,)
+
+ return outputs
+
+
+MULTIMODAL1_TEXT_START_DOCSTRING = r"""
+ This model inherits from [`PreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) subclass.
+ Use it as a regular PyTorch Module and refer to the PyTorch documentation for all matter related to general usage
+ and behavior.
+
+ Parameters:
+ config ([`Multimodal1TextConfig`]):
+ Model configuration class with all the parameters of the model. Initializing with a config file does not
+ load the weights associated with the model, only the configuration. Check out the
+ [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+
+@add_start_docstrings(
+ "The bare Multimodal1Text Model outputting raw hidden-states without any specific head on top.",
+ MULTIMODAL1_TEXT_START_DOCSTRING,
+)
+class Multimodal1TextPreTrainedModel(PreTrainedModel):
+ config_class = Multimodal1TextConfig
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["Multimodal1TextDecoderLayer"]
+ _skip_keys_device_placement = ["past_key_values"]
+ _supports_flash_attn_2 = True
+ _supports_sdpa = True
+ _supports_cache_class = True
+ _supports_quantized_cache = True
+ _supports_static_cache = True
+
+ def _init_weights(self, module):
+ std = self.config.initializer_range
+ if isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+
+
+MULTIMODAL1_TEXT_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you provide
+ it.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ If `past_key_values` is used, optionally only the last `input_ids` have to be input (see
+ `past_key_values`).
+
+ If you want to change padding behavior, you should read [`modeling_opt._prepare_decoder_attention_mask`]
+ and modify to your needs. See diagram 1 in [the paper](https://arxiv.org/abs/1910.13461) for more
+ information on the default strategy.
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ position_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.n_positions - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ past_key_values (`Cache` or `tuple(tuple(torch.FloatTensor))`, *optional*):
+ Pre-computed hidden-states (key and values in the self-attention blocks and in the cross-attention
+ blocks) that can be used to speed up sequential decoding. This typically consists in the `past_key_values`
+ returned by the model at a previous stage of decoding, when `use_cache=True` or `config.use_cache=True`.
+
+ Two formats are allowed:
+ - a [`~cache_utils.Cache`] instance, see our
+ [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache);
+ - Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of
+ shape `(batch_size, num_heads, sequence_length, embed_size_per_head)`). This is also known as the legacy
+ cache format.
+
+ The model will output the same cache format that is fed as input. If no `past_key_values` are passed, the
+ legacy cache format will be returned.
+
+ If `past_key_values` are used, the user can optionally input only the last `input_ids` (those that don't
+ have their past key value states given to this model) of shape `(batch_size, 1)` instead of all `input_ids`
+ of shape `(batch_size, sequence_length)`.
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see
+ `past_key_values`).
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*):
+ Indices depicting the position of the input sequence tokens in the sequence. Contrarily to `position_ids`,
+ this tensor is not affected by padding. It is used to update the cache in the correct position and to infer
+ the complete sequence length.
+"""
+
+
+@add_start_docstrings(
+ "The bare Multimodal1Text Model outputting raw hidden-states without any specific head on top.",
+ MULTIMODAL1_TEXT_START_DOCSTRING,
+)
+class Multimodal1TextModel(Multimodal1TextPreTrainedModel):
+ """
+ Transformer decoder consisting of *config.num_hidden_layers* layers. Each layer is a [`Multimodal1TextDecoderLayer`]
+
+ Args:
+ config: Multimodal1TextConfig
+ """
+
+ def __init__(self, config: Multimodal1TextConfig):
+ super().__init__(config)
+ self.padding_idx = config.pad_token_id
+ self.vocab_size = config.vocab_size
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx)
+ self.layers = nn.ModuleList(
+ [Multimodal1TextDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)]
+ )
+ self.norm = Multimodal1TextRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.rotary_emb = Multimodal1TextRotaryEmbedding(config=config)
+ self.gradient_checkpointing = False
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embed_tokens
+
+ def set_input_embeddings(self, value):
+ self.embed_tokens = value
+
+ @add_start_docstrings_to_model_forward(MULTIMODAL1_TEXT_INPUTS_DOCSTRING)
+ def forward(
+ self,
+ input_ids: torch.LongTensor = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **flash_attn_kwargs: Unpack[FlashAttentionKwargs],
+ ) -> Union[Tuple, BaseModelOutputWithPast]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError("You must specify exactly one of input_ids or inputs_embeds")
+
+ if self.gradient_checkpointing and self.training and use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`."
+ )
+ use_cache = False
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ if use_cache and past_key_values is None:
+ past_key_values = DynamicCache()
+
+ if cache_position is None:
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ cache_position = torch.arange(
+ past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device
+ )
+
+ if position_ids is None:
+ position_ids = cache_position.unsqueeze(0)
+
+ causal_mask = self._update_causal_mask(
+ attention_mask, inputs_embeds, cache_position, past_key_values, output_attentions
+ )
+
+ hidden_states = inputs_embeds
+
+ # create position embeddings to be shared across the decoder layers
+ position_embeddings = self.rotary_emb(hidden_states, position_ids)
+
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+
+ for decoder_layer in self.layers[: self.config.num_hidden_layers]:
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ if self.gradient_checkpointing and self.training:
+ layer_outputs = self._gradient_checkpointing_func(
+ decoder_layer.__call__,
+ hidden_states,
+ causal_mask,
+ position_ids,
+ past_key_values,
+ output_attentions,
+ use_cache,
+ cache_position,
+ position_embeddings,
+ )
+ else:
+ layer_outputs = decoder_layer(
+ hidden_states,
+ attention_mask=causal_mask,
+ position_ids=position_ids,
+ past_key_value=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ position_embeddings=position_embeddings,
+ **flash_attn_kwargs,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attns += (layer_outputs[1],)
+
+ hidden_states = self.norm(hidden_states)
+
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ output = BaseModelOutputWithPast(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values if use_cache else None,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ )
+ return output if return_dict else output.to_tuple()
+
+ def _update_causal_mask(
+ self,
+ attention_mask: torch.Tensor,
+ input_tensor: torch.Tensor,
+ cache_position: torch.Tensor,
+ past_key_values: Cache,
+ output_attentions: bool,
+ ):
+ if self.config._attn_implementation == "flash_attention_2":
+ if attention_mask is not None and (attention_mask == 0.0).any():
+ return attention_mask
+ return None
+
+ # For SDPA, when possible, we will rely on its `is_causal` argument instead of its `attn_mask` argument, in
+ # order to dispatch on Flash Attention 2. This feature is not compatible with static cache, as SDPA will fail
+ # to infer the attention mask.
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ using_static_cache = isinstance(past_key_values, StaticCache)
+
+ # When output attentions is True, sdpa implementation's forward method calls the eager implementation's forward
+ if self.config._attn_implementation == "sdpa" and not using_static_cache and not output_attentions:
+ if AttentionMaskConverter._ignore_causal_mask_sdpa(
+ attention_mask,
+ inputs_embeds=input_tensor,
+ past_key_values_length=past_seen_tokens,
+ is_training=self.training,
+ ):
+ return None
+
+ dtype, device = input_tensor.dtype, input_tensor.device
+ sequence_length = input_tensor.shape[1]
+ if using_static_cache:
+ target_length = past_key_values.get_max_cache_shape()
+ else:
+ target_length = (
+ attention_mask.shape[-1]
+ if isinstance(attention_mask, torch.Tensor)
+ else past_seen_tokens + sequence_length + 1
+ )
+
+ # In case the provided `attention` mask is 2D, we generate a causal mask here (4D).
+ causal_mask = self._prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask,
+ sequence_length=sequence_length,
+ target_length=target_length,
+ dtype=dtype,
+ device=device,
+ cache_position=cache_position,
+ batch_size=input_tensor.shape[0],
+ )
+
+ if (
+ self.config._attn_implementation == "sdpa"
+ and attention_mask is not None
+ and attention_mask.device.type == "cuda"
+ and not output_attentions
+ ):
+ # Attend to all tokens in fully masked rows in the causal_mask, for example the relevant first rows when
+ # using left padding. This is required by F.scaled_dot_product_attention memory-efficient attention path.
+ # Details: https://github.com/pytorch/pytorch/issues/110213
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = AttentionMaskConverter._unmask_unattended(causal_mask, min_dtype)
+
+ return causal_mask
+
+ @staticmethod
+ def _prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask: torch.Tensor,
+ sequence_length: int,
+ target_length: int,
+ dtype: torch.dtype,
+ device: torch.device,
+ cache_position: torch.Tensor,
+ batch_size: int,
+ **kwargs,
+ ):
+ """
+ Creates a causal 4D mask of shape `(batch_size, 1, query_length, key_value_length)` from a 2D mask of shape
+ `(batch_size, key_value_length)`, or if the input `attention_mask` is already 4D, do nothing.
+
+ Args:
+ attention_mask (`torch.Tensor`):
+ A 2D attention mask of shape `(batch_size, key_value_length)` or a 4D attention mask of shape
+ `(batch_size, 1, query_length, key_value_length)`.
+ sequence_length (`int`):
+ The sequence length being processed.
+ target_length (`int`):
+ The target length: when generating with static cache, the mask should be as long as the static cache,
+ to account for the 0 padding, the part of the cache that is not filled yet.
+ dtype (`torch.dtype`):
+ The dtype to use for the 4D attention mask.
+ device (`torch.device`):
+ The device to plcae the 4D attention mask on.
+ cache_position (`torch.Tensor`):
+ Indices depicting the position of the input sequence tokens in the sequence.
+ batch_size (`torch.Tensor`):
+ Batch size.
+ """
+ if attention_mask is not None and attention_mask.dim() == 4:
+ # In this case we assume that the mask comes already in inverted form and requires no inversion or slicing.
+ causal_mask = attention_mask
+ else:
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = torch.full(
+ (sequence_length, target_length), fill_value=min_dtype, dtype=dtype, device=device
+ )
+ if sequence_length != 1:
+ causal_mask = torch.triu(causal_mask, diagonal=1)
+ causal_mask *= torch.arange(target_length, device=device) > cache_position.reshape(-1, 1)
+ causal_mask = causal_mask[None, None, :, :].expand(batch_size, 1, -1, -1)
+ if attention_mask is not None:
+ causal_mask = causal_mask.clone() # copy to contiguous memory for in-place edit
+ mask_length = attention_mask.shape[-1]
+ padding_mask = causal_mask[:, :, :, :mask_length] + attention_mask[:, None, None, :]
+ padding_mask = padding_mask == 0
+ causal_mask[:, :, :, :mask_length] = causal_mask[:, :, :, :mask_length].masked_fill(
+ padding_mask, min_dtype
+ )
+
+ return causal_mask
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_multimodal2.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_multimodal2.py
new file mode 100644
index 0000000000000000000000000000000000000000..b10b11b671af95ea8109622fda1fd4fe1523e8a3
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_multimodal2.py
@@ -0,0 +1,705 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from examples/modular-transformers/modular_multimodal2.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_multimodal2.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+
+from typing import Optional, Tuple, Union
+
+import torch
+from torch import nn
+
+from transformers.utils import add_start_docstrings
+
+from ...activations import ACT2FN
+from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPooling
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import is_torch_greater_or_equal_than_2_2
+from ...utils import (
+ add_start_docstrings_to_model_forward,
+ is_flash_attn_2_available,
+ is_flash_attn_greater_or_equal_2_10,
+ logging,
+ replace_return_docstrings,
+ torch_int,
+)
+from .configuration_multimodal2 import Multimodal2Config, Multimodal2VisionConfig
+
+
+if is_flash_attn_2_available():
+ from ...modeling_flash_attention_utils import _flash_attention_forward
+
+
+logger = logging.get_logger(__name__)
+
+
+class Multimodal2VisionAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.embed_dim = config.hidden_size
+ self.num_heads = config.num_attention_heads
+ self.head_dim = self.embed_dim // self.num_heads
+ if self.head_dim * self.num_heads != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`:"
+ f" {self.num_heads})."
+ )
+ self.scale = self.head_dim**-0.5
+ self.dropout = config.attention_dropout
+
+ self.k_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.v_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.q_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.out_proj = nn.Linear(self.embed_dim, self.embed_dim)
+
+ def _shape(self, tensor: torch.Tensor, seq_len: int, bsz: int):
+ return tensor.view(bsz, seq_len, self.num_heads, self.head_dim).transpose(1, 2).contiguous()
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ causal_attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.Tensor, Optional[torch.Tensor]]:
+ """Input shape: Batch x Time x Channel"""
+
+ bsz, tgt_len, embed_dim = hidden_states.size()
+
+ # get query proj
+ query_states = self.q_proj(hidden_states) * self.scale
+ key_states = self._shape(self.k_proj(hidden_states), -1, bsz)
+ value_states = self._shape(self.v_proj(hidden_states), -1, bsz)
+
+ proj_shape = (bsz * self.num_heads, -1, self.head_dim)
+ query_states = self._shape(query_states, tgt_len, bsz).view(*proj_shape)
+ key_states = key_states.view(*proj_shape)
+ value_states = value_states.view(*proj_shape)
+
+ src_len = key_states.size(1)
+ attn_weights = torch.bmm(query_states, key_states.transpose(1, 2))
+
+ if attn_weights.size() != (bsz * self.num_heads, tgt_len, src_len):
+ raise ValueError(
+ f"Attention weights should be of size {(bsz * self.num_heads, tgt_len, src_len)}, but is"
+ f" {attn_weights.size()}"
+ )
+
+ # apply the causal_attention_mask first
+ if causal_attention_mask is not None:
+ if causal_attention_mask.size() != (bsz, 1, tgt_len, src_len):
+ raise ValueError(
+ f"Attention mask should be of size {(bsz, 1, tgt_len, src_len)}, but is"
+ f" {causal_attention_mask.size()}"
+ )
+ attn_weights = attn_weights.view(bsz, self.num_heads, tgt_len, src_len) + causal_attention_mask
+ attn_weights = attn_weights.view(bsz * self.num_heads, tgt_len, src_len)
+
+ if attention_mask is not None:
+ if attention_mask.size() != (bsz, 1, tgt_len, src_len):
+ raise ValueError(
+ f"Attention mask should be of size {(bsz, 1, tgt_len, src_len)}, but is {attention_mask.size()}"
+ )
+ attn_weights = attn_weights.view(bsz, self.num_heads, tgt_len, src_len) + attention_mask
+ attn_weights = attn_weights.view(bsz * self.num_heads, tgt_len, src_len)
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1)
+
+ if output_attentions:
+ # this operation is a bit akward, but it's required to
+ # make sure that attn_weights keeps its gradient.
+ # In order to do so, attn_weights have to reshaped
+ # twice and have to be reused in the following
+ attn_weights_reshaped = attn_weights.view(bsz, self.num_heads, tgt_len, src_len)
+ attn_weights = attn_weights_reshaped.view(bsz * self.num_heads, tgt_len, src_len)
+ else:
+ attn_weights_reshaped = None
+
+ attn_probs = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training)
+
+ attn_output = torch.bmm(attn_probs, value_states)
+
+ if attn_output.size() != (bsz * self.num_heads, tgt_len, self.head_dim):
+ raise ValueError(
+ f"`attn_output` should be of size {(bsz, self.num_heads, tgt_len, self.head_dim)}, but is"
+ f" {attn_output.size()}"
+ )
+
+ attn_output = attn_output.view(bsz, self.num_heads, tgt_len, self.head_dim)
+ attn_output = attn_output.transpose(1, 2)
+ attn_output = attn_output.reshape(bsz, tgt_len, embed_dim)
+
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights_reshaped
+
+
+class Multimodal2VisionSdpaAttention(Multimodal2VisionAttention):
+ """
+ SDPA attention module using torch.nn.functional.scaled_dot_product_attention. This module inherits from
+ `Multimodal2VisionAttention` as the weights of the module stays untouched. The only changes are on the forward pass to adapt to
+ SDPA API.
+ """
+
+ # Adapted from Multimodal2VisionAttention.forward
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ causal_attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.Tensor, Optional[torch.Tensor]]:
+ if output_attentions:
+ # TODO: Improve this warning with e.g. `model.config.attn_implementation = "manual"` once this is implemented.
+ logger.warning_once(
+ "Multimodal2VisionModel is using Multimodal2VisionSdpaAttention, but `torch.nn.functional.scaled_dot_product_attention` does not "
+ "support `output_attentions=True`. Falling back to the manual attention implementation, but specifying "
+ "the manual implementation will be required from Transformers version v5.0.0 onwards. This warning can "
+ 'be removed using the argument `attn_implementation="eager"` when loading the model.'
+ )
+ return super().forward(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ causal_attention_mask=causal_attention_mask,
+ output_attentions=output_attentions,
+ )
+
+ # MULTIMODAL2_VISION text model uses both `causal_attention_mask` and `attention_mask`
+ if attention_mask is not None and causal_attention_mask is not None:
+ attn_mask = attention_mask + causal_attention_mask
+ elif causal_attention_mask is not None:
+ attn_mask = causal_attention_mask
+ else:
+ attn_mask = attention_mask
+
+ bsz, tgt_len, embed_dim = hidden_states.size()
+
+ query_states = self.q_proj(hidden_states)
+ key_states = self.k_proj(hidden_states)
+ value_states = self.v_proj(hidden_states)
+
+ query_states = query_states.view(bsz, -1, self.num_heads, self.head_dim).transpose(1, 2)
+ key_states = key_states.view(bsz, -1, self.num_heads, self.head_dim).transpose(1, 2)
+ value_states = value_states.view(bsz, -1, self.num_heads, self.head_dim).transpose(1, 2)
+
+ # SDPA with memory-efficient backend is currently (torch==2.1.2) bugged with non-contiguous inputs with custom attn_mask,
+ # Reference: https://github.com/pytorch/pytorch/issues/112577.
+ if not is_torch_greater_or_equal_than_2_2 and query_states.device.type == "cuda" and attn_mask is not None:
+ query_states = query_states.contiguous()
+ key_states = key_states.contiguous()
+ value_states = value_states.contiguous()
+
+ # MULTIMODAL2_VISION text model uses both `causal_attention_mask` and `attention_mask` sequentially.
+ attn_output = torch.nn.functional.scaled_dot_product_attention(
+ query_states,
+ key_states,
+ value_states,
+ attn_mask=attn_mask,
+ dropout_p=self.dropout if self.training else 0.0,
+ scale=self.scale,
+ )
+
+ attn_output = attn_output.transpose(1, 2)
+ attn_output = attn_output.reshape(bsz, tgt_len, embed_dim)
+
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, None
+
+
+class Multimodal2VisionFlashAttention2(Multimodal2VisionAttention):
+ """
+ Multimodal2VisionAttention flash attention module. This module inherits from `Multimodal2VisionAttention` as the weights of the module stays
+ untouched. The only required change would be on the forward pass where it needs to correctly call the public API of
+ flash attention and deal with padding tokens in case the input contains any of them.
+ """
+
+ def __init__(self, *args, **kwargs):
+ super().__init__(*args, **kwargs)
+
+ # TODO: Should be removed once Flash Attention for RoCm is bumped to 2.1.
+ # flash_attn<2.1 generates top-left aligned causal mask, while what is needed here is bottom-right alignement, that was made default for flash_attn>=2.1. This attribute is used to handle this difference. Reference: https://github.com/Dao-AILab/flash-attention/releases/tag/v2.1.0.
+ # Beware that with flash_attn<2.1, using q_seqlen != k_seqlen (except for the case q_seqlen == 1) produces a wrong mask (top-left).
+ self._flash_attn_uses_top_left_mask = not is_flash_attn_greater_or_equal_2_10()
+
+ # Adapted from transformers.models.llama.modeling_llama.LlamaFlashAttention2.forward
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ causal_attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.Tensor, Optional[torch.Tensor]]:
+ output_attentions = False
+
+ batch_size, q_len, _ = hidden_states.size()
+
+ query_states = self.q_proj(hidden_states)
+ key_states = self.k_proj(hidden_states)
+ value_states = self.v_proj(hidden_states)
+
+ # Flash attention requires the input to have the shape
+ # batch_size x seq_length x head_dim x hidden_dim
+ # therefore we just need to keep the original shape
+ query_states = query_states.view(batch_size, q_len, self.num_heads, self.head_dim)
+ key_states = key_states.view(batch_size, q_len, self.num_heads, self.head_dim)
+ value_states = value_states.view(batch_size, q_len, self.num_heads, self.head_dim)
+
+ dropout_rate = self.dropout if self.training else 0.0
+
+ # In PEFT, usually we cast the layer norms in float32 for training stability reasons
+ # therefore the input hidden states gets silently casted in float32. Hence, we need
+ # cast them back in the correct dtype just to be sure everything works as expected.
+ # This might slowdown training & inference so it is recommended to not cast the LayerNorms
+ # in fp32.
+
+ input_dtype = query_states.dtype
+ if input_dtype == torch.float32:
+ if torch.is_autocast_enabled():
+ target_dtype = torch.get_autocast_gpu_dtype()
+ # Handle the case where the model is quantized
+ elif hasattr(self.config, "_pre_quantization_dtype"):
+ target_dtype = self.config._pre_quantization_dtype
+ else:
+ target_dtype = self.q_proj.weight.dtype
+
+ logger.warning_once(
+ f"The input hidden states seems to be silently casted in float32, this might be related to"
+ f" the fact you have upcasted embedding or layer norm layers in float32. We will cast back the input in"
+ f" {target_dtype}."
+ )
+
+ query_states = query_states.to(target_dtype)
+ key_states = key_states.to(target_dtype)
+ value_states = value_states.to(target_dtype)
+
+ attn_output = _flash_attention_forward(
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ q_len,
+ dropout=dropout_rate,
+ is_causal=causal_attention_mask is not None,
+ use_top_left_mask=self._flash_attn_uses_top_left_mask,
+ )
+
+ attn_output = attn_output.reshape(batch_size, q_len, self.embed_dim).contiguous()
+ attn_output = self.out_proj(attn_output)
+
+ if not output_attentions:
+ attn_weights = None
+
+ return attn_output, attn_weights
+
+
+class Multimodal2VisionMLP(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.activation_fn = ACT2FN[config.hidden_act]
+ self.fc1 = nn.Linear(config.hidden_size, config.intermediate_size)
+ self.fc2 = nn.Linear(config.intermediate_size, config.hidden_size)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.fc1(hidden_states)
+ hidden_states = self.activation_fn(hidden_states)
+ hidden_states = self.fc2(hidden_states)
+ return hidden_states
+
+
+MULTIMODAL2_VISION_ATTENTION_CLASSES = {
+ "eager": Multimodal2VisionAttention,
+ "sdpa": Multimodal2VisionSdpaAttention,
+ "flash_attention_2": Multimodal2VisionFlashAttention2,
+}
+
+
+class Multimodal2VisionEncoderLayer(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.embed_dim = config.hidden_size
+ self.self_attn = MULTIMODAL2_VISION_ATTENTION_CLASSES[config._attn_implementation](config)
+ self.layer_norm1 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
+ self.mlp = Multimodal2VisionMLP(config)
+ self.layer_norm2 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: torch.Tensor,
+ causal_attention_mask: torch.Tensor,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.FloatTensor]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ `(config.encoder_attention_heads,)`.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+
+ hidden_states = self.layer_norm1(hidden_states)
+ hidden_states, attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ causal_attention_mask=causal_attention_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.layer_norm2(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class Multimodal2VisionEncoder(nn.Module):
+ """
+ Transformer encoder consisting of `config.num_hidden_layers` self attention layers. Each layer is a
+ [`Multimodal2VisionEncoderLayer`].
+
+ Args:
+ config: Multimodal2VisionConfig
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.layers = nn.ModuleList([Multimodal2VisionEncoderLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ inputs_embeds,
+ attention_mask: Optional[torch.Tensor] = None,
+ causal_attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[Tuple, BaseModelOutput]:
+ r"""
+ Args:
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `input_ids` indices into associated vectors
+ than the model's internal embedding lookup matrix.
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ causal_attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Causal mask for the text model. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ encoder_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ hidden_states = inputs_embeds
+ for idx, encoder_layer in enumerate(self.layers):
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+ if self.gradient_checkpointing and self.training:
+ layer_outputs = self._gradient_checkpointing_func(
+ encoder_layer.__call__,
+ hidden_states,
+ attention_mask,
+ causal_attention_mask,
+ output_attentions,
+ )
+ else:
+ layer_outputs = encoder_layer(
+ hidden_states,
+ attention_mask,
+ causal_attention_mask,
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions
+ )
+
+
+class Multimodal2VisionEmbeddings(nn.Module):
+ def __init__(self, config: Multimodal2VisionConfig):
+ super().__init__()
+ self.config = config
+ self.embed_dim = config.hidden_size
+ self.image_size = config.image_size
+ self.patch_size = config.patch_size
+
+ self.class_embedding = nn.Parameter(torch.randn(self.embed_dim))
+
+ self.patch_embedding = nn.Conv2d(
+ in_channels=config.num_channels,
+ out_channels=self.embed_dim,
+ kernel_size=self.patch_size,
+ stride=self.patch_size,
+ bias=False,
+ )
+
+ self.num_patches = (self.image_size // self.patch_size) ** 2
+ self.num_positions = self.num_patches + 1
+ self.position_embedding = nn.Embedding(self.num_positions, self.embed_dim)
+ self.register_buffer("position_ids", torch.arange(self.num_positions).expand((1, -1)), persistent=False)
+
+ def interpolate_pos_encoding(self, embeddings: torch.Tensor, height: int, width: int) -> torch.Tensor:
+ """
+ This method allows to interpolate the pre-trained position encodings, to be able to use the model on higher resolution
+ images. This method is also adapted to support torch.jit tracing.
+
+ Adapted from:
+ - https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174-L194, and
+ - https://github.com/facebookresearch/dinov2/blob/e1277af2ba9496fbadf7aec6eba56e8d882d1e35/dinov2/models/vision_transformer.py#L179-L211
+ """
+
+ num_patches = embeddings.shape[1] - 1
+ position_embedding = self.position_embedding.weight.unsqueeze(0)
+ num_positions = position_embedding.shape[1] - 1
+
+ # always interpolate when tracing to ensure the exported model works for dynamic input shapes
+ if not torch.jit.is_tracing() and num_patches == num_positions and height == width:
+ return self.position_embedding(self.position_ids)
+
+ class_pos_embed = position_embedding[:, :1]
+ patch_pos_embed = position_embedding[:, 1:]
+
+ dim = embeddings.shape[-1]
+
+ new_height = height // self.patch_size
+ new_width = width // self.patch_size
+
+ sqrt_num_positions = torch_int(num_positions**0.5)
+ patch_pos_embed = patch_pos_embed.reshape(1, sqrt_num_positions, sqrt_num_positions, dim)
+ patch_pos_embed = patch_pos_embed.permute(0, 3, 1, 2)
+
+ patch_pos_embed = nn.functional.interpolate(
+ patch_pos_embed,
+ size=(new_height, new_width),
+ mode="bicubic",
+ align_corners=False,
+ )
+
+ patch_pos_embed = patch_pos_embed.permute(0, 2, 3, 1).view(1, -1, dim)
+
+ return torch.cat((class_pos_embed, patch_pos_embed), dim=1)
+
+ def forward(self, pixel_values: torch.FloatTensor, interpolate_pos_encoding=False) -> torch.Tensor:
+ batch_size, _, height, width = pixel_values.shape
+ if not interpolate_pos_encoding and (height != self.image_size or width != self.image_size):
+ raise ValueError(
+ f"Input image size ({height}*{width}) doesn't match model" f" ({self.image_size}*{self.image_size})."
+ )
+ target_dtype = self.patch_embedding.weight.dtype
+ patch_embeds = self.patch_embedding(pixel_values.to(dtype=target_dtype)) # shape = [*, width, grid, grid]
+ patch_embeds = patch_embeds.flatten(2).transpose(1, 2)
+
+ class_embeds = self.class_embedding.expand(batch_size, 1, -1)
+ embeddings = torch.cat([class_embeds, patch_embeds], dim=1)
+ if interpolate_pos_encoding:
+ embeddings = embeddings + self.interpolate_pos_encoding(embeddings, height, width)
+ else:
+ embeddings = embeddings + self.position_embedding(self.position_ids)
+ return embeddings
+
+
+MULTIMODAL2_VISION_INPUTS_DOCSTRING = r"""
+ Args:
+ pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`):
+ Pixel values. Padding will be ignored by default should you provide it. Pixel values can be obtained using
+ [`AutoImageProcessor`]. See [`Multimodal2ImageProcessor.__call__`] for details.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ interpolate_pos_encoding (`bool`, *optional*, defaults `False`):
+ Whether to interpolate the pre-trained position encodings.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+
+class Multimodal2VisionTransformer(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ embed_dim = config.hidden_size
+
+ self.embeddings = Multimodal2VisionEmbeddings(config)
+ self.pre_layrnorm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.encoder = Multimodal2VisionEncoder(config)
+ self.post_layernorm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+
+ @add_start_docstrings_to_model_forward(MULTIMODAL2_VISION_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=BaseModelOutputWithPooling, config_class=Multimodal2VisionConfig)
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ interpolate_pos_encoding: Optional[bool] = False,
+ ) -> Union[Tuple, BaseModelOutputWithPooling]:
+ r"""
+ Returns:
+
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if pixel_values is None:
+ raise ValueError("You have to specify pixel_values")
+
+ hidden_states = self.embeddings(pixel_values, interpolate_pos_encoding=interpolate_pos_encoding)
+ hidden_states = self.pre_layrnorm(hidden_states)
+
+ encoder_outputs = self.encoder(
+ inputs_embeds=hidden_states,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ last_hidden_state = encoder_outputs[0]
+ pooled_output = last_hidden_state[:, 0, :]
+ pooled_output = self.post_layernorm(pooled_output)
+
+ if not return_dict:
+ return (last_hidden_state, pooled_output) + encoder_outputs[1:]
+
+ return BaseModelOutputWithPooling(
+ last_hidden_state=last_hidden_state,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+class Multimodal2VisionPreTrainedModel(PreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = Multimodal2Config
+ base_model_prefix = "multimodal2_vision"
+ supports_gradient_checkpointing = True
+ _supports_sdpa = True
+ _supports_flash_attn_2 = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, Multimodal2VisionMLP):
+ pass
+
+
+MULTIMODAL2_VISION_START_DOCSTRING = "doc"
+
+
+@add_start_docstrings("New doc", MULTIMODAL2_VISION_START_DOCSTRING)
+class Multimodal2VisionModel(Multimodal2VisionPreTrainedModel):
+ config_class = Multimodal2VisionConfig
+ main_input_name = "pixel_values"
+ _no_split_modules = ["Multimodal2VisionEncoderLayer"]
+
+ def __init__(self, config: Multimodal2VisionConfig):
+ super().__init__(config)
+ self.vision_model = Multimodal2VisionTransformer(config)
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self) -> nn.Module:
+ return self.vision_model.embeddings.patch_embedding
+
+ @add_start_docstrings_to_model_forward(MULTIMODAL2_VISION_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=BaseModelOutputWithPooling, config_class=Multimodal2VisionConfig)
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ interpolate_pos_encoding: bool = False,
+ return_dict: Optional[bool] = None,
+ ) -> Union[Tuple, BaseModelOutputWithPooling]:
+ r"""
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import AutoProcessor, Multimodal2VisionModel
+
+ >>> model = Multimodal2VisionModel.from_pretrained("openai/multimodal2-vit-base-patch32")
+ >>> processor = AutoProcessor.from_pretrained("openai/multimodal2-vit-base-patch32")
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> inputs = processor(images=image, return_tensors="pt")
+
+ >>> outputs = model(**inputs)
+ >>> last_hidden_state = outputs.last_hidden_state
+ >>> pooled_output = outputs.pooler_output # pooled CLS states
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ return self.vision_model(
+ pixel_values=pixel_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ )
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_my_new_model2.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_my_new_model2.py
new file mode 100644
index 0000000000000000000000000000000000000000..9288b1a29305780150859fe6653aab44d888099a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_my_new_model2.py
@@ -0,0 +1,819 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from examples/modular-transformers/modular_my_new_model2.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_my_new_model2.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+from typing import Callable, List, Optional, Tuple, Union
+
+import torch
+from torch import nn
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache, StaticCache
+from ...modeling_attn_mask_utils import AttentionMaskConverter
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_outputs import BaseModelOutputWithPast, SequenceClassifierOutputWithPast
+from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import add_start_docstrings, add_start_docstrings_to_model_forward, logging
+from .configuration_my_new_model2 import MyNewModel2Config
+
+
+logger = logging.get_logger(__name__)
+
+
+class MyNewModel2RMSNorm(nn.Module):
+ def __init__(self, dim: int, eps: float = 1e-6):
+ super().__init__()
+ self.eps = eps
+ self.weight = nn.Parameter(torch.zeros(dim))
+
+ def _norm(self, x):
+ return x * torch.rsqrt(x.pow(2).mean(-1, keepdim=True) + self.eps)
+
+ def forward(self, x):
+ output = self._norm(x.float())
+ # Llama does x.to(float16) * w whilst MyNewModel2 is (x * w).to(float16)
+ # See https://github.com/huggingface/transformers/pull/29402
+ output = output * (1.0 + self.weight.float())
+ return output.type_as(x)
+
+ def extra_repr(self):
+ return f"{tuple(self.weight.shape)}, eps={self.eps}"
+
+
+class MyNewModel2MLP(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.hidden_size = config.hidden_size
+ self.intermediate_size = config.intermediate_size
+ self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False)
+ self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False)
+ self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=False)
+ self.act_fn = ACT2FN[config.hidden_act]
+
+ def forward(self, x):
+ down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x))
+ return down_proj
+
+
+class MyNewModel2RotaryEmbedding(nn.Module):
+ def __init__(
+ self,
+ config: MyNewModel2Config,
+ device=None,
+ ):
+ super().__init__()
+ self.rope_kwargs = {}
+ # BC: "rope_type" was originally "type"
+ if hasattr(config, "rope_scaling") and config.rope_scaling is not None:
+ self.rope_type = config.rope_scaling.get("rope_type", config.rope_scaling.get("type"))
+ else:
+ self.rope_type = "default"
+ self.max_seq_len_cached = config.max_position_embeddings
+ self.original_max_seq_len = config.max_position_embeddings
+
+ self.config = config
+ self.rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type]
+
+ inv_freq, self.attention_scaling = self.rope_init_fn(self.config, device, **self.rope_kwargs)
+ self.register_buffer("inv_freq", inv_freq, persistent=False)
+ self.original_inv_freq = self.inv_freq
+
+ def _dynamic_frequency_update(self, position_ids, device):
+ """
+ dynamic RoPE layers should recompute `inv_freq` in the following situations:
+ 1 - growing beyond the cached sequence length (allow scaling)
+ 2 - the current sequence length is in the original scale (avoid losing precision with small sequences)
+ """
+ seq_len = torch.max(position_ids) + 1
+ if seq_len > self.max_seq_len_cached: # growth
+ inv_freq, self.attention_scaling = self.rope_init_fn(
+ self.config, device, seq_len=seq_len, **self.rope_kwargs
+ )
+ self.register_buffer("inv_freq", inv_freq, persistent=False) # TODO joao: may break with compilation
+ self.max_seq_len_cached = seq_len
+
+ if seq_len < self.original_max_seq_len and self.max_seq_len_cached > self.original_max_seq_len: # reset
+ self.register_buffer("inv_freq", self.original_inv_freq, persistent=False)
+ self.max_seq_len_cached = self.original_max_seq_len
+
+ @torch.no_grad()
+ def forward(self, x, position_ids):
+ if "dynamic" in self.rope_type:
+ self._dynamic_frequency_update(position_ids, device=x.device)
+
+ # Core RoPE block
+ inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1)
+ position_ids_expanded = position_ids[:, None, :].float()
+ # Force float32 (see https://github.com/huggingface/transformers/pull/29285)
+ device_type = x.device.type
+ device_type = device_type if isinstance(device_type, str) and device_type != "mps" else "cpu"
+ with torch.autocast(device_type=device_type, enabled=False):
+ freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2)
+ emb = torch.cat((freqs, freqs), dim=-1)
+ cos = emb.cos()
+ sin = emb.sin()
+
+ # Advanced RoPE types (e.g. yarn) apply a post-processing scaling factor, equivalent to scaling attention
+ cos = cos * self.attention_scaling
+ sin = sin * self.attention_scaling
+
+ return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype)
+
+
+def rotate_half(x):
+ """Rotates half the hidden dims of the input."""
+ x1 = x[..., : x.shape[-1] // 2]
+ x2 = x[..., x.shape[-1] // 2 :]
+ return torch.cat((-x2, x1), dim=-1)
+
+
+def apply_rotary_pos_emb(q, k, cos, sin, position_ids=None, unsqueeze_dim=1):
+ """Applies Rotary Position Embedding to the query and key tensors.
+
+ Args:
+ q (`torch.Tensor`): The query tensor.
+ k (`torch.Tensor`): The key tensor.
+ cos (`torch.Tensor`): The cosine part of the rotary embedding.
+ sin (`torch.Tensor`): The sine part of the rotary embedding.
+ position_ids (`torch.Tensor`, *optional*):
+ Deprecated and unused.
+ unsqueeze_dim (`int`, *optional*, defaults to 1):
+ The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and
+ sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note
+ that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and
+ k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes
+ cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have
+ the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2.
+ Returns:
+ `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding.
+ """
+ cos = cos.unsqueeze(unsqueeze_dim)
+ sin = sin.unsqueeze(unsqueeze_dim)
+ q_embed = (q * cos) + (rotate_half(q) * sin)
+ k_embed = (k * cos) + (rotate_half(k) * sin)
+ return q_embed, k_embed
+
+
+def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor:
+ """
+ This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch,
+ num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim)
+ """
+ batch, num_key_value_heads, slen, head_dim = hidden_states.shape
+ if n_rep == 1:
+ return hidden_states
+ hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim)
+ return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim)
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ key_states = repeat_kv(key, module.num_key_value_groups)
+ value_states = repeat_kv(value, module.num_key_value_groups)
+
+ attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling
+ if attention_mask is not None:
+ causal_mask = attention_mask[:, :, :, : key_states.shape[-2]]
+ attn_weights = attn_weights + causal_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value_states)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class MyNewModel2Attention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config: MyNewModel2Config, layer_idx: int):
+ super().__init__()
+ self.config = config
+ self.layer_idx = layer_idx
+ self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads)
+ self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads
+ self.scaling = self.head_dim**-0.5
+ self.attention_dropout = config.attention_dropout
+ self.is_causal = True
+
+ self.q_proj = nn.Linear(
+ config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.k_proj = nn.Linear(
+ config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.v_proj = nn.Linear(
+ config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.o_proj = nn.Linear(
+ config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_bias
+ )
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ position_embeddings: Tuple[torch.Tensor, torch.Tensor],
+ attention_mask: Optional[torch.Tensor],
+ past_key_value: Optional[Cache] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> Tuple[torch.Tensor, Optional[torch.Tensor], Optional[Tuple[torch.Tensor]]]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+
+ query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ cos, sin = position_embeddings
+ query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin)
+
+ if past_key_value is not None:
+ # sin and cos are specific to RoPE models; cache_position needed for the static cache
+ cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position}
+ key_states, value_states = past_key_value.update(key_states, value_states, self.layer_idx, cache_kwargs)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ if self.config._attn_implementation == "sdpa" and kwargs.get("output_attentions", False):
+ logger.warning_once(
+ "`torch.nn.functional.scaled_dot_product_attention` does not support `output_attentions=True`. Falling back to "
+ 'eager attention. This warning can be removed using the argument `attn_implementation="eager"` when loading the model.'
+ )
+ else:
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.attention_dropout,
+ scaling=self.scaling,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ return attn_output, attn_weights
+
+
+class MyNewModel2DecoderLayer(nn.Module):
+ def __init__(self, config: MyNewModel2Config, layer_idx: int):
+ super().__init__()
+ self.hidden_size = config.hidden_size
+
+ self.self_attn = MyNewModel2Attention(config=config, layer_idx=layer_idx)
+
+ self.mlp = MyNewModel2MLP(config)
+ self.input_layernorm = MyNewModel2RMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.post_attention_layernorm = MyNewModel2RMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_value: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = False,
+ cache_position: Optional[torch.LongTensor] = None,
+ position_embeddings: Optional[Tuple[torch.Tensor, torch.Tensor]] = None, # necessary, but kept here for BC
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> Tuple[torch.FloatTensor, Optional[Tuple[torch.FloatTensor, torch.FloatTensor]]]:
+ residual = hidden_states
+
+ hidden_states = self.input_layernorm(hidden_states)
+
+ # Self Attention
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_value=past_key_value,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ position_embeddings=position_embeddings,
+ **kwargs,
+ )
+ hidden_states = residual + hidden_states
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.post_attention_layernorm(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+ if output_attentions:
+ outputs += (self_attn_weights,)
+
+ return outputs
+
+
+MY_NEW_MODEL2_START_DOCSTRING = r"""
+ This model inherits from [`PreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) subclass.
+ Use it as a regular PyTorch Module and refer to the PyTorch documentation for all matter related to general usage
+ and behavior.
+
+ Parameters:
+ config ([`MyNewModel2Config`]):
+ Model configuration class with all the parameters of the model. Initializing with a config file does not
+ load the weights associated with the model, only the configuration. Check out the
+ [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+
+@add_start_docstrings(
+ "The bare MyNewModel2 Model outputting raw hidden-states without any specific head on top.",
+ MY_NEW_MODEL2_START_DOCSTRING,
+)
+class MyNewModel2PreTrainedModel(PreTrainedModel):
+ config_class = MyNewModel2Config
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["MyNewModel2DecoderLayer"]
+ _skip_keys_device_placement = ["past_key_values"]
+ _supports_flash_attn_2 = True
+ _supports_sdpa = True
+ _supports_cache_class = True
+ _supports_quantized_cache = True
+ _supports_static_cache = True
+
+ def _init_weights(self, module):
+ std = self.config.initializer_range
+ if isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+
+
+MY_NEW_MODEL2_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you provide
+ it.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ If `past_key_values` is used, optionally only the last `input_ids` have to be input (see
+ `past_key_values`).
+
+ If you want to change padding behavior, you should read [`modeling_opt._prepare_decoder_attention_mask`]
+ and modify to your needs. See diagram 1 in [the paper](https://arxiv.org/abs/1910.13461) for more
+ information on the default strategy.
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ position_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.n_positions - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ past_key_values (`Cache` or `tuple(tuple(torch.FloatTensor))`, *optional*):
+ Pre-computed hidden-states (key and values in the self-attention blocks and in the cross-attention
+ blocks) that can be used to speed up sequential decoding. This typically consists in the `past_key_values`
+ returned by the model at a previous stage of decoding, when `use_cache=True` or `config.use_cache=True`.
+
+ Two formats are allowed:
+ - a [`~cache_utils.Cache`] instance, see our
+ [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache);
+ - Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of
+ shape `(batch_size, num_heads, sequence_length, embed_size_per_head)`). This is also known as the legacy
+ cache format.
+
+ The model will output the same cache format that is fed as input. If no `past_key_values` are passed, the
+ legacy cache format will be returned.
+
+ If `past_key_values` are used, the user can optionally input only the last `input_ids` (those that don't
+ have their past key value states given to this model) of shape `(batch_size, 1)` instead of all `input_ids`
+ of shape `(batch_size, sequence_length)`.
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see
+ `past_key_values`).
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*):
+ Indices depicting the position of the input sequence tokens in the sequence. Contrarily to `position_ids`,
+ this tensor is not affected by padding. It is used to update the cache in the correct position and to infer
+ the complete sequence length.
+"""
+
+
+@add_start_docstrings(
+ "The bare MyNewModel2 Model outputting raw hidden-states without any specific head on top.",
+ MY_NEW_MODEL2_START_DOCSTRING,
+)
+class MyNewModel2Model(MyNewModel2PreTrainedModel):
+ """
+ Transformer decoder consisting of *config.num_hidden_layers* layers. Each layer is a [`MyNewModel2DecoderLayer`]
+
+ Args:
+ config: MyNewModel2Config
+ """
+
+ def __init__(self, config: MyNewModel2Config):
+ super().__init__(config)
+ self.padding_idx = config.pad_token_id
+ self.vocab_size = config.vocab_size
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx)
+ self.layers = nn.ModuleList(
+ [MyNewModel2DecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)]
+ )
+ self.norm = MyNewModel2RMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.rotary_emb = MyNewModel2RotaryEmbedding(config=config)
+ self.gradient_checkpointing = False
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embed_tokens
+
+ def set_input_embeddings(self, value):
+ self.embed_tokens = value
+
+ @add_start_docstrings_to_model_forward(MY_NEW_MODEL2_INPUTS_DOCSTRING)
+ def forward(
+ self,
+ input_ids: torch.LongTensor = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Union[Cache, List[torch.FloatTensor]]] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[Tuple, BaseModelOutputWithPast]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError("You must specify exactly one of input_ids or inputs_embeds")
+
+ if self.gradient_checkpointing and self.training and use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`."
+ )
+ use_cache = False
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ if use_cache and past_key_values is None:
+ past_key_values = DynamicCache()
+
+ if cache_position is None:
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ cache_position = torch.arange(
+ past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device
+ )
+
+ if position_ids is None:
+ position_ids = cache_position.unsqueeze(0)
+
+ causal_mask = self._update_causal_mask(
+ attention_mask, inputs_embeds, cache_position, past_key_values, output_attentions
+ )
+
+ # embed positions
+ hidden_states = inputs_embeds
+
+ # create position embeddings to be shared across the decoder layers
+ position_embeddings = self.rotary_emb(hidden_states, position_ids)
+
+ # normalized
+ # MyNewModel2 downcasts the below to float16, causing sqrt(3072)=55.4256 to become 55.5
+ # See https://github.com/huggingface/transformers/pull/29402
+ normalizer = torch.tensor(self.config.hidden_size**0.5, dtype=hidden_states.dtype)
+ hidden_states = hidden_states * normalizer
+
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+
+ for decoder_layer in self.layers[: self.config.num_hidden_layers]:
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ if self.gradient_checkpointing and self.training:
+ layer_outputs = self._gradient_checkpointing_func(
+ decoder_layer.__call__,
+ hidden_states,
+ causal_mask,
+ position_ids,
+ past_key_values,
+ output_attentions,
+ use_cache,
+ cache_position,
+ position_embeddings,
+ )
+ else:
+ layer_outputs = decoder_layer(
+ hidden_states,
+ attention_mask=causal_mask,
+ position_ids=position_ids,
+ past_key_value=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ position_embeddings=position_embeddings,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attns += (layer_outputs[1],)
+
+ hidden_states = self.norm(hidden_states)
+
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ output = BaseModelOutputWithPast(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values if use_cache else None,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ )
+ return output if return_dict else output.to_tuple()
+
+ def _update_causal_mask(
+ self,
+ attention_mask: torch.Tensor,
+ input_tensor: torch.Tensor,
+ cache_position: torch.Tensor,
+ past_key_values: Cache,
+ output_attentions: bool,
+ ):
+ if self.config._attn_implementation == "flash_attention_2":
+ if attention_mask is not None and (attention_mask == 0.0).any():
+ return attention_mask
+ return None
+
+ # For SDPA, when possible, we will rely on its `is_causal` argument instead of its `attn_mask` argument, in
+ # order to dispatch on Flash Attention 2. This feature is not compatible with static cache, as SDPA will fail
+ # to infer the attention mask.
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ using_static_cache = isinstance(past_key_values, StaticCache)
+
+ # When output attentions is True, sdpa implementation's forward method calls the eager implementation's forward
+ if self.config._attn_implementation == "sdpa" and not using_static_cache and not output_attentions:
+ if AttentionMaskConverter._ignore_causal_mask_sdpa(
+ attention_mask,
+ inputs_embeds=input_tensor,
+ past_key_values_length=past_seen_tokens,
+ is_training=self.training,
+ ):
+ return None
+
+ dtype, device = input_tensor.dtype, input_tensor.device
+ sequence_length = input_tensor.shape[1]
+ if using_static_cache:
+ target_length = past_key_values.get_max_cache_shape()
+ else:
+ target_length = (
+ attention_mask.shape[-1]
+ if isinstance(attention_mask, torch.Tensor)
+ else past_seen_tokens + sequence_length + 1
+ )
+
+ # In case the provided `attention` mask is 2D, we generate a causal mask here (4D).
+ causal_mask = self._prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask,
+ sequence_length=sequence_length,
+ target_length=target_length,
+ dtype=dtype,
+ device=device,
+ cache_position=cache_position,
+ batch_size=input_tensor.shape[0],
+ )
+
+ if (
+ self.config._attn_implementation == "sdpa"
+ and attention_mask is not None
+ and attention_mask.device.type == "cuda"
+ and not output_attentions
+ ):
+ # Attend to all tokens in fully masked rows in the causal_mask, for example the relevant first rows when
+ # using left padding. This is required by F.scaled_dot_product_attention memory-efficient attention path.
+ # Details: https://github.com/pytorch/pytorch/issues/110213
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = AttentionMaskConverter._unmask_unattended(causal_mask, min_dtype)
+
+ return causal_mask
+
+ @staticmethod
+ def _prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask: torch.Tensor,
+ sequence_length: int,
+ target_length: int,
+ dtype: torch.dtype,
+ device: torch.device,
+ cache_position: torch.Tensor,
+ batch_size: int,
+ **kwargs,
+ ):
+ """
+ Creates a causal 4D mask of shape `(batch_size, 1, query_length, key_value_length)` from a 2D mask of shape
+ `(batch_size, key_value_length)`, or if the input `attention_mask` is already 4D, do nothing.
+
+ Args:
+ attention_mask (`torch.Tensor`):
+ A 2D attention mask of shape `(batch_size, key_value_length)` or a 4D attention mask of shape
+ `(batch_size, 1, query_length, key_value_length)`.
+ sequence_length (`int`):
+ The sequence length being processed.
+ target_length (`int`):
+ The target length: when generating with static cache, the mask should be as long as the static cache,
+ to account for the 0 padding, the part of the cache that is not filled yet.
+ dtype (`torch.dtype`):
+ The dtype to use for the 4D attention mask.
+ device (`torch.device`):
+ The device to plcae the 4D attention mask on.
+ cache_position (`torch.Tensor`):
+ Indices depicting the position of the input sequence tokens in the sequence.
+ batch_size (`torch.Tensor`):
+ Batch size.
+ """
+ if attention_mask is not None and attention_mask.dim() == 4:
+ # In this case we assume that the mask comes already in inverted form and requires no inversion or slicing.
+ causal_mask = attention_mask
+ else:
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = torch.full(
+ (sequence_length, target_length), fill_value=min_dtype, dtype=dtype, device=device
+ )
+ if sequence_length != 1:
+ causal_mask = torch.triu(causal_mask, diagonal=1)
+ causal_mask *= torch.arange(target_length, device=device) > cache_position.reshape(-1, 1)
+ causal_mask = causal_mask[None, None, :, :].expand(batch_size, 1, -1, -1)
+ if attention_mask is not None:
+ causal_mask = causal_mask.clone() # copy to contiguous memory for in-place edit
+ mask_length = attention_mask.shape[-1]
+ padding_mask = causal_mask[:, :, :, :mask_length] + attention_mask[:, None, None, :]
+ padding_mask = padding_mask == 0
+ causal_mask[:, :, :, :mask_length] = causal_mask[:, :, :, :mask_length].masked_fill(
+ padding_mask, min_dtype
+ )
+
+ return causal_mask
+
+
+@add_start_docstrings(
+ """
+ The MyNewModel2 Model transformer with a sequence classification head on top (linear layer).
+
+ [`MyNewModel2ForSequenceClassification`] uses the last token in order to do the classification, as other causal models
+ (e.g. GPT-2) do.
+
+ Since it does classification on the last token, it requires to know the position of the last token. If a
+ `pad_token_id` is defined in the configuration, it finds the last token that is not a padding token in each row. If
+ no `pad_token_id` is defined, it simply takes the last value in each row of the batch. Since it cannot guess the
+ padding tokens when `inputs_embeds` are passed instead of `input_ids`, it does the same (take the last value in
+ each row of the batch).
+ """,
+ MY_NEW_MODEL2_START_DOCSTRING,
+)
+class MyNewModel2ForSequenceClassification(MyNewModel2PreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+ self.model = MyNewModel2Model(config)
+ self.score = nn.Linear(config.hidden_size, self.num_labels, bias=False)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.model.embed_tokens
+
+ def set_input_embeddings(self, value):
+ self.model.embed_tokens = value
+
+ @add_start_docstrings_to_model_forward(MY_NEW_MODEL2_INPUTS_DOCSTRING)
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Union[Cache, List[torch.FloatTensor]]] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[Tuple, SequenceClassifierOutputWithPast]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ transformer_outputs = self.model(
+ input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ hidden_states = transformer_outputs[0]
+ logits = self.score(hidden_states)
+
+ if input_ids is not None:
+ batch_size = input_ids.shape[0]
+ else:
+ batch_size = inputs_embeds.shape[0]
+
+ if self.config.pad_token_id is None and batch_size != 1:
+ raise ValueError("Cannot handle batch sizes > 1 if no padding token is defined.")
+ if self.config.pad_token_id is None:
+ sequence_lengths = -1
+ else:
+ if input_ids is not None:
+ # if no pad token found, use modulo instead of reverse indexing for ONNX compatibility
+ sequence_lengths = torch.eq(input_ids, self.config.pad_token_id).int().argmax(-1) - 1
+ sequence_lengths = sequence_lengths % input_ids.shape[-1]
+ sequence_lengths = sequence_lengths.to(logits.device)
+ else:
+ sequence_lengths = -1
+
+ pooled_logits = logits[torch.arange(batch_size, device=logits.device), sequence_lengths]
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(logits=logits, labels=labels, pooled_logits=pooled_logits, config=self.config)
+
+ if not return_dict:
+ output = (pooled_logits,) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutputWithPast(
+ loss=loss,
+ logits=pooled_logits,
+ past_key_values=transformer_outputs.past_key_values,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_new_task_model.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_new_task_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..477d084b1d93094b0c83c07ff6b772e532671641
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_new_task_model.py
@@ -0,0 +1,470 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from examples/modular-transformers/modular_new_task_model.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_new_task_model.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+from dataclasses import dataclass
+from typing import ClassVar, List, Optional, Tuple, Union
+
+import torch
+from torch import nn
+
+from ...cache_utils import Cache, HybridCache, StaticCache
+from ...generation import GenerationMixin
+from ...modeling_utils import PreTrainedModel
+from ...utils import (
+ ModelOutput,
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ replace_return_docstrings,
+)
+from ..auto import AutoModel, AutoModelForCausalLM
+from .configuration_new_task_model import NewTaskModelConfig
+
+
+_CONFIG_FOR_DOC = "NewTaskModelConfig"
+
+
+@dataclass
+class NewTaskModelCausalLMOutputWithPast(ModelOutput):
+ """
+ Base class for NewTaskModelcausal language model (or autoregressive) outputs.
+
+ Args:
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided):
+ Language modeling loss (for next-token prediction).
+ logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.text_config.vocab_size)`):
+ Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
+ past_key_values (`tuple(tuple(torch.FloatTensor))`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`):
+ Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of shape
+ `(batch_size, num_heads, sequence_length, embed_size_per_head)`)
+
+ Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see
+ `past_key_values` input) to speed up sequential decoding.
+ hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, +
+ one for the output of each layer) of shape `(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the optional initial embedding outputs.
+ attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ image_hidden_states (`torch.FloatTensor`, *optional*):
+ A `torch.FloatTensor` of size `(batch_size, num_images, sequence_length, hidden_size)`.
+ image_hidden_states of the model produced by the vision encoder after projecting last hidden state.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: torch.FloatTensor = None
+ past_key_values: Optional[Union[List[torch.FloatTensor], Cache]] = None
+ hidden_states: Optional[Tuple[torch.FloatTensor]] = None
+ attentions: Optional[Tuple[torch.FloatTensor]] = None
+ image_hidden_states: Optional[torch.FloatTensor] = None
+
+
+class NewTaskModelMultiModalProjector(nn.Module):
+ def __init__(self, config: NewTaskModelConfig):
+ super().__init__()
+ self.linear = nn.Linear(config.vision_config.hidden_size, config.vision_config.projection_dim, bias=True)
+
+ def forward(self, image_features):
+ hidden_states = self.linear(image_features)
+
+ return hidden_states
+
+
+NEW_TASK_MODEL_START_DOCSTRING = r"""
+ This model inherits from [`PreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) subclass.
+ Use it as a regular PyTorch Module and refer to the PyTorch documentation for all matter related to general usage
+ and behavior.
+
+ Parameters:
+ config ([`NewTaskModelConfig`] or [`NewTaskModelVisionConfig`]):
+ Model configuration class with all the parameters of the model. Initializing with a config file does not
+ load the weights associated with the model, only the configuration. Check out the
+ [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+
+@add_start_docstrings(
+ "The bare LLaMA Model outputting raw hidden-states without any specific head on top.",
+ NEW_TASK_MODEL_START_DOCSTRING,
+)
+class NewTaskModelPreTrainedModel(PreTrainedModel):
+ config_class = NewTaskModelConfig
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["NewTaskModelMultiModalProjector"]
+ _skip_keys_device_placement = "past_key_values"
+ _supports_cache_class = True
+ _supports_quantized_cache = True
+ _supports_static_cache = True
+ _supports_cache_class = True
+ _supports_flash_attn_2 = True
+ _supports_sdpa = True
+
+ def _init_weights(self, module):
+ # important: this ported version of NewTaskModelisn't meant for training from scratch - only
+ # inference and fine-tuning
+ std = (
+ self.config.initializer_range
+ if hasattr(self.config, "initializer_range")
+ else self.config.text_config.initializer_range
+ )
+
+ if hasattr(module, "class_embedding"):
+ module.class_embedding.data.normal_(mean=0.0, std=std)
+
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+
+
+NEW_TASK_MODEL_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you provide
+ it.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)):
+ The tensors corresponding to the input images. Pixel values can be obtained using
+ [`AutoImageProcessor`]. See [`SiglipImageProcessor.__call__`] for details ([]`NewTaskModelProcessor`] uses
+ [`SiglipImageProcessor`] for processing images).
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ If `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+
+ If you want to change padding behavior, you should read [`modeling_opt._prepare_decoder_attention_mask`]
+ and modify to your needs. See diagram 1 in [the paper](https://arxiv.org/abs/1910.13461) for more
+ information on the default strategy.
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ position_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.n_positions - 1]`. [What are position IDs?](../glossary#position-ids)
+ past_key_values (`tuple(tuple(torch.FloatTensor))`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`):
+ Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of shape
+ `(batch_size, num_heads, sequence_length, embed_size_per_head)`) and 2 additional tensors of shape
+ `(batch_size, num_heads, encoder_sequence_length, embed_size_per_head)`.
+
+ Contains pre-computed hidden-states (key and values in the self-attention blocks and in the cross-attention
+ blocks) that can be used (see `past_key_values` input) to speed up sequential decoding.
+
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those that
+ don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of all
+ `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see
+ `past_key_values`).
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*):
+ Indices depicting the position of the input sequence tokens in the sequence. Contrarily to `position_ids`,
+ this tensor is not affected by padding. It is used to update the cache in the correct position and to infer
+ the complete sequence length.
+"""
+
+
+@add_start_docstrings(
+ """The NEW_TASK_MODEL model which consists of a vision backbone and a language model.""",
+ NEW_TASK_MODEL_START_DOCSTRING,
+)
+class NewTaskModelForNewTask(NewTaskModelPreTrainedModel, GenerationMixin):
+ main_input_name: ClassVar[str] = "doc_input_ids" # transformers-related
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.vision_tower = AutoModel.from_config(config=config.vision_config)
+ self.multi_modal_projector = NewTaskModelMultiModalProjector(config)
+ self.vocab_size = config.text_config.vocab_size
+
+ language_model = AutoModelForCausalLM.from_config(config=config.text_config)
+
+ if language_model._tied_weights_keys is not None:
+ self._tied_weights_keys = [f"language_model.{k}" for k in language_model._tied_weights_keys]
+ self.language_model = language_model
+
+ self.pad_token_id = self.config.pad_token_id if self.config.pad_token_id is not None else -1
+
+ self.embedding_dim = self.config.embedding_dim
+ self.custom_text_proj = nn.Linear(self.config.text_config.hidden_size, self.embedding_dim)
+
+ if self.language_model._tied_weights_keys is not None:
+ self._tied_weights_keys = [f"model.language_model.{k}" for k in self.language_model._tied_weights_keys]
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.language_model.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.language_model.set_input_embeddings(value)
+
+ def get_output_embeddings(self):
+ return self.language_model.get_output_embeddings()
+
+ def set_output_embeddings(self, new_embeddings):
+ self.language_model.set_output_embeddings(new_embeddings)
+
+ def set_decoder(self, decoder):
+ self.language_model.set_decoder(decoder)
+
+ def get_decoder(self):
+ return self.language_model.get_decoder()
+
+ def tie_weights(self):
+ return self.language_model.tie_weights()
+
+ def _update_causal_mask(
+ self,
+ attention_mask,
+ token_type_ids,
+ past_key_values,
+ cache_position,
+ input_ids=None,
+ inputs_embeds=None,
+ is_training: bool = False,
+ ):
+ if self.config.text_config._attn_implementation == "flash_attention_2":
+ if attention_mask is not None and 0.0 in attention_mask:
+ return attention_mask
+ return None
+
+ using_static_cache = isinstance(past_key_values, StaticCache)
+ min_dtype = torch.finfo(self.dtype).min
+ inputs_lead_dim = input_ids.shape[0] if input_ids is not None else inputs_embeds.shape[0]
+ sequence_length = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1]
+ if using_static_cache:
+ target_length = past_key_values.get_max_cache_shape()
+ elif isinstance(past_key_values, HybridCache):
+ target_length = past_key_values.get_max_cache_shape()
+ else:
+ target_length = (
+ attention_mask.shape[-1]
+ if isinstance(attention_mask, torch.Tensor)
+ else cache_position[0] + sequence_length + 1
+ )
+
+ if attention_mask is not None and attention_mask.dim() == 4:
+ # In this case we assume that the mask comes already in inverted form and requires no inversion or slicing.
+ return attention_mask
+
+ causal_mask = torch.full(
+ (sequence_length, target_length), fill_value=min_dtype, dtype=self.dtype, device=cache_position.device
+ )
+ # Causal diagonal mask only if training, otherwise attend to the whole prefix. Training-specific attn for prefix is handled below
+ if sequence_length != 1:
+ if is_training:
+ causal_mask = torch.triu(causal_mask, diagonal=1)
+ else:
+ causal_mask[:, :sequence_length] = 0.0
+
+ causal_mask *= torch.arange(target_length, device=cache_position.device) > cache_position.reshape(-1, 1)
+ causal_mask = causal_mask[None, None, :, :].expand(inputs_lead_dim, 1, -1, -1)
+ if attention_mask is not None:
+ causal_mask = causal_mask.clone() # copy to contiguous memory for in-place edit
+ mask_length = attention_mask.shape[-1]
+ padding_mask = causal_mask[:, :, :, :mask_length] + attention_mask[:, None, None, :].to(causal_mask.device)
+ padding_mask = padding_mask == 0
+ causal_mask[:, :, :, :mask_length] = causal_mask[:, :, :, :mask_length].masked_fill(
+ padding_mask, min_dtype
+ )
+ # we are training thus we need to create a full mask on the image + prefix but causal on suffix
+ if is_training:
+ causal_mask[:, :, :, :mask_length] = causal_mask[:, :, :, :mask_length].masked_fill(
+ token_type_ids[:, None, None, :].to(causal_mask.device) == 0, 0
+ )
+ return causal_mask
+
+ def get_image_features(self, pixel_values: torch.FloatTensor):
+ """
+ Obtains image last hidden states from the vision tower and apply multimodal projection.
+
+ Args:
+ pixel_values (`torch.FloatTensor]` of shape `(batch_size, channels, height, width)`)
+ The tensors corresponding to the input images.
+ Returns:
+ image_features (`torch.Tensor`): Image feature tensor of shape `(num_images, image_length, embed_dim)`).
+ """
+ image_outputs = self.vision_tower(pixel_values)
+ selected_image_feature = image_outputs.last_hidden_state
+ image_features = self.multi_modal_projector(selected_image_feature)
+ image_features = image_features / (self.config.text_config.hidden_size**0.5)
+ return image_features
+
+ @add_start_docstrings_to_model_forward(NEW_TASK_MODEL_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=NewTaskModelCausalLMOutputWithPast, config_class=_CONFIG_FOR_DOC)
+ def forward(
+ self,
+ input_ids: torch.LongTensor = None,
+ pixel_values: torch.FloatTensor = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Union[List[torch.FloatTensor], Cache]] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ num_logits_to_keep: int = 0,
+ ) -> Union[Tuple, NewTaskModelCausalLMOutputWithPast]:
+ r"""
+ Args:
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should either be in `[0, ...,
+ config.text_config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.text_config.vocab_size]`.
+
+ num_logits_to_keep (`int`, *optional*):
+ Calculate logits for the last `num_logits_to_keep` tokens. If `0`, calculate logits for all
+ `input_ids` (special case). Only last token logits are needed for generation, and calculating them only for that
+ token can save memory, which becomes pretty significant for long sequences or large vocabulary size.
+
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import AutoProcessor, NewTaskModelForNewTask
+
+ >>> model = NewTaskModelForNewTask.from_pretrained("google/NewTaskModel-test-224px-hf")
+ >>> processor = AutoProcessor.from_pretrained("google/NewTaskModel-test-224px-hf")
+
+ >>> prompt = "answer en Where is the cow standing?"
+ >>> url = "https://huggingface.co/gv-hf/NewTaskModel-test-224px-hf/resolve/main/cow_beach_1.png"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> inputs = processor(images=image, text=prompt, return_tensors="pt")
+
+ >>> # Generate
+ >>> generate_ids = model.generate(**inputs, max_length=30)
+ >>> processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
+ "answer en Where is the cow standing?\nbeach"
+ ```
+ Returns:
+ """
+ vlm_outputs = super().forward(
+ input_ids=input_ids,
+ pixel_values=pixel_values,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ token_type_ids=token_type_ids,
+ cache_position=cache_position,
+ inputs_embeds=inputs_embeds,
+ labels=labels,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=True,
+ return_dict=True,
+ num_logits_to_keep=num_logits_to_keep,
+ )
+ last_hidden_states = vlm_outputs.hidden_states[-1] # (batch_size, sequence_length, hidden_size)
+ proj = self.custom_text_proj(last_hidden_states) # (batch_size, sequence_length, dim)
+
+ # L2 normalization
+ embeddings = proj / proj.norm(dim=-1, keepdim=True) # (batch_size, sequence_length, dim)
+
+ embeddings = embeddings * attention_mask.unsqueeze(-1) # (batch_size, sequence_length, dim)
+
+ return (embeddings,) + vlm_outputs
+
+ def prepare_inputs_for_generation(
+ self,
+ input_ids,
+ past_key_values=None,
+ inputs_embeds=None,
+ cache_position=None,
+ position_ids=None,
+ pixel_values=None,
+ attention_mask=None,
+ token_type_ids=None,
+ use_cache=True,
+ num_logits_to_keep=None,
+ labels=None,
+ **kwargs,
+ ):
+ # Overwritten -- custom `position_ids` and `pixel_values` handling
+ model_inputs = self.language_model.prepare_inputs_for_generation(
+ input_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ cache_position=cache_position,
+ use_cache=use_cache,
+ num_logits_to_keep=num_logits_to_keep,
+ token_type_ids=token_type_ids,
+ **kwargs,
+ )
+
+ # position_ids in NewTaskModel are 1-indexed
+ if model_inputs.get("position_ids") is not None:
+ model_inputs["position_ids"] += 1
+ # If we're in cached decoding stage, pixel values should be None because input ids do not contain special image token anymore
+ # Otherwise we need pixel values to be passed to model. NOTE: use_cache=False needs pixel_values always
+ if cache_position[0] == 0:
+ model_inputs["pixel_values"] = pixel_values
+ is_training = token_type_ids is not None and labels is not None
+ if cache_position[0] == 0 and isinstance(past_key_values, HybridCache):
+ causal_mask = self._update_causal_mask(
+ attention_mask, token_type_ids, past_key_values, cache_position, input_ids, inputs_embeds, is_training
+ )
+ model_inputs["attention_mask"] = causal_mask
+ return model_inputs
+
+ def resize_token_embeddings(
+ self,
+ new_num_tokens: Optional[int] = None,
+ pad_to_multiple_of=None,
+ ) -> nn.Embedding:
+ model_embeds = self.language_model.resize_token_embeddings(new_num_tokens, pad_to_multiple_of)
+
+ # Update vocab size
+ self.config.text_config.vocab_size = model_embeds.num_embeddings
+ self.config.vocab_size = model_embeds.num_embeddings
+ self.vocab_size = model_embeds.num_embeddings
+
+ return model_embeds
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_roberta.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_roberta.py
new file mode 100644
index 0000000000000000000000000000000000000000..e50cf60c3a4ed4b450cd7093a42822d232dcb774
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_roberta.py
@@ -0,0 +1,1014 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from examples/modular-transformers/modular_roberta.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_roberta.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+import math
+import os
+from typing import List, Optional, Tuple, Union
+
+import torch
+import torch.nn as nn
+from packaging import version
+
+from ...activations import ACT2FN
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask_for_sdpa, _prepare_4d_causal_attention_mask_for_sdpa
+from ...modeling_outputs import BaseModelOutputWithPastAndCrossAttentions, BaseModelOutputWithPoolingAndCrossAttentions
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import apply_chunking_to_forward, find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import (
+ add_code_sample_docstrings,
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ get_torch_version,
+ logging,
+)
+from .configuration_roberta import RobertaConfig
+
+
+logger = logging.get_logger(__name__)
+
+_CHECKPOINT_FOR_DOC = "google-roberta/roberta-base-uncased"
+_CONFIG_FOR_DOC = "RobertaConfig"
+
+
+class RobertaEmbeddings(nn.Module):
+ """Construct the embeddings from word, position and token_type embeddings."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id)
+ self.position_embeddings = nn.Embedding(
+ config.max_position_embeddings, config.hidden_size, config.pad_token_id
+ )
+ self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.hidden_size)
+
+ # self.LayerNorm is not snake-cased to stick with TensorFlow model variable name and be able to load
+ # any TensorFlow checkpoint file
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ # position_ids (1, len position emb) is contiguous in memory and exported when serialized
+ self.position_embedding_type = getattr(config, "position_embedding_type", "absolute")
+ self.register_buffer(
+ "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False
+ )
+ self.register_buffer(
+ "token_type_ids", torch.zeros(self.position_ids.size(), dtype=torch.long), persistent=False
+ )
+ self.pad_token_id = config.pad_token_id
+
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ past_key_values_length: int = 0,
+ ) -> torch.Tensor:
+ if input_ids is not None:
+ input_shape = input_ids.size()
+ else:
+ input_shape = inputs_embeds.size()[:-1]
+
+ seq_length = input_shape[1]
+
+ if position_ids is None:
+ position_ids = self.position_ids[:, past_key_values_length : seq_length + past_key_values_length]
+
+ # Setting the token_type_ids to the registered buffer in constructor where it is all zeros, which usually occurs
+ # when its auto-generated, registered buffer helps users when tracing the model without passing token_type_ids, solves
+ # issue #5664
+ if token_type_ids is None:
+ if hasattr(self, "token_type_ids"):
+ buffered_token_type_ids = self.token_type_ids[:, :seq_length]
+ buffered_token_type_ids_expanded = buffered_token_type_ids.expand(input_shape[0], seq_length)
+ token_type_ids = buffered_token_type_ids_expanded
+ else:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device)
+
+ if inputs_embeds is None:
+ inputs_embeds = self.word_embeddings(input_ids)
+ token_type_embeddings = self.token_type_embeddings(token_type_ids)
+
+ embeddings = inputs_embeds + token_type_embeddings
+ if self.position_embedding_type == "absolute":
+ position_embeddings = self.position_embeddings(position_ids)
+ embeddings += position_embeddings
+ embeddings = self.LayerNorm(embeddings)
+ embeddings = self.dropout(embeddings)
+ return embeddings
+
+
+class RobertaSelfAttention(nn.Module):
+ def __init__(self, config, position_embedding_type=None):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention "
+ f"heads ({config.num_attention_heads})"
+ )
+
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size)
+
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+ self.position_embedding_type = position_embedding_type or getattr(
+ config, "position_embedding_type", "absolute"
+ )
+ if self.position_embedding_type == "relative_key" or self.position_embedding_type == "relative_key_query":
+ self.max_position_embeddings = config.max_position_embeddings
+ self.distance_embedding = nn.Embedding(2 * config.max_position_embeddings - 1, self.attention_head_size)
+
+ self.is_decoder = config.is_decoder
+
+ def transpose_for_scores(self, x: torch.Tensor) -> torch.Tensor:
+ new_x_shape = x.size()[:-1] + (self.num_attention_heads, self.attention_head_size)
+ x = x.view(new_x_shape)
+ return x.permute(0, 2, 1, 3)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ past_key_value: Optional[Tuple[Tuple[torch.FloatTensor]]] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.Tensor]:
+ mixed_query_layer = self.query(hidden_states)
+
+ # If this is instantiated as a cross-attention module, the keys
+ # and values come from an encoder; the attention mask needs to be
+ # such that the encoder's padding tokens are not attended to.
+ is_cross_attention = encoder_hidden_states is not None
+
+ if is_cross_attention and past_key_value is not None:
+ # reuse k,v, cross_attentions
+ key_layer = past_key_value[0]
+ value_layer = past_key_value[1]
+ attention_mask = encoder_attention_mask
+ elif is_cross_attention:
+ key_layer = self.transpose_for_scores(self.key(encoder_hidden_states))
+ value_layer = self.transpose_for_scores(self.value(encoder_hidden_states))
+ attention_mask = encoder_attention_mask
+ elif past_key_value is not None:
+ key_layer = self.transpose_for_scores(self.key(hidden_states))
+ value_layer = self.transpose_for_scores(self.value(hidden_states))
+ key_layer = torch.cat([past_key_value[0], key_layer], dim=2)
+ value_layer = torch.cat([past_key_value[1], value_layer], dim=2)
+ else:
+ key_layer = self.transpose_for_scores(self.key(hidden_states))
+ value_layer = self.transpose_for_scores(self.value(hidden_states))
+
+ query_layer = self.transpose_for_scores(mixed_query_layer)
+
+ use_cache = past_key_value is not None
+ if self.is_decoder:
+ # if cross_attention save Tuple(torch.Tensor, torch.Tensor) of all cross attention key/value_states.
+ # Further calls to cross_attention layer can then reuse all cross-attention
+ # key/value_states (first "if" case)
+ # if uni-directional self-attention (decoder) save Tuple(torch.Tensor, torch.Tensor) of
+ # all previous decoder key/value_states. Further calls to uni-directional self-attention
+ # can concat previous decoder key/value_states to current projected key/value_states (third "elif" case)
+ # if encoder bi-directional self-attention `past_key_value` is always `None`
+ past_key_value = (key_layer, value_layer)
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2))
+
+ if self.position_embedding_type == "relative_key" or self.position_embedding_type == "relative_key_query":
+ query_length, key_length = query_layer.shape[2], key_layer.shape[2]
+ if use_cache:
+ position_ids_l = torch.tensor(key_length - 1, dtype=torch.long, device=hidden_states.device).view(
+ -1, 1
+ )
+ else:
+ position_ids_l = torch.arange(query_length, dtype=torch.long, device=hidden_states.device).view(-1, 1)
+ position_ids_r = torch.arange(key_length, dtype=torch.long, device=hidden_states.device).view(1, -1)
+ distance = position_ids_l - position_ids_r
+
+ positional_embedding = self.distance_embedding(distance + self.max_position_embeddings - 1)
+ positional_embedding = positional_embedding.to(dtype=query_layer.dtype) # fp16 compatibility
+
+ if self.position_embedding_type == "relative_key":
+ relative_position_scores = torch.einsum("bhld,lrd->bhlr", query_layer, positional_embedding)
+ attention_scores = attention_scores + relative_position_scores
+ elif self.position_embedding_type == "relative_key_query":
+ relative_position_scores_query = torch.einsum("bhld,lrd->bhlr", query_layer, positional_embedding)
+ relative_position_scores_key = torch.einsum("bhrd,lrd->bhlr", key_layer, positional_embedding)
+ attention_scores = attention_scores + relative_position_scores_query + relative_position_scores_key
+
+ attention_scores = attention_scores / math.sqrt(self.attention_head_size)
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in RobertaModel forward() function)
+ attention_scores = attention_scores + attention_mask
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = nn.functional.softmax(attention_scores, dim=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(attention_probs)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = attention_probs * head_mask
+
+ context_layer = torch.matmul(attention_probs, value_layer)
+
+ context_layer = context_layer.permute(0, 2, 1, 3).contiguous()
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.view(new_context_layer_shape)
+
+ outputs = (context_layer, attention_probs) if output_attentions else (context_layer,)
+
+ if self.is_decoder:
+ outputs = outputs + (past_key_value,)
+ return outputs
+
+
+class RobertaSdpaSelfAttention(RobertaSelfAttention):
+ def __init__(self, config, position_embedding_type=None):
+ super().__init__(config, position_embedding_type=position_embedding_type)
+ self.dropout_prob = config.attention_probs_dropout_prob
+ self.require_contiguous_qkv = version.parse(get_torch_version()) < version.parse("2.2.0")
+
+ # Adapted from RobertaSelfAttention
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ past_key_value: Optional[Tuple[Tuple[torch.FloatTensor]]] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.Tensor]:
+ if self.position_embedding_type != "absolute" or output_attentions or head_mask is not None:
+ # TODO: Improve this warning with e.g. `model.config._attn_implementation = "manual"` once implemented.
+ logger.warning_once(
+ "RobertaSdpaSelfAttention is used but `torch.nn.functional.scaled_dot_product_attention` does not support "
+ "non-absolute `position_embedding_type` or `output_attentions=True` or `head_mask`. Falling back to "
+ "the manual attention implementation, but specifying the manual implementation will be required from "
+ "Transformers version v5.0.0 onwards. This warning can be removed using the argument "
+ '`attn_implementation="eager"` when loading the model.'
+ )
+ return super().forward(
+ hidden_states,
+ attention_mask,
+ head_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ past_key_value,
+ output_attentions,
+ )
+
+ bsz, tgt_len, _ = hidden_states.size()
+
+ query_layer = self.transpose_for_scores(self.query(hidden_states))
+
+ # If this is instantiated as a cross-attention module, the keys and values come from an encoder; the attention
+ # mask needs to be such that the encoder's padding tokens are not attended to.
+ is_cross_attention = encoder_hidden_states is not None
+
+ current_states = encoder_hidden_states if is_cross_attention else hidden_states
+ attention_mask = encoder_attention_mask if is_cross_attention else attention_mask
+
+ # Check `seq_length` of `past_key_value` == `len(current_states)` to support prefix tuning
+ if is_cross_attention and past_key_value and past_key_value[0].shape[2] == current_states.shape[1]:
+ key_layer, value_layer = past_key_value
+ else:
+ key_layer = self.transpose_for_scores(self.key(current_states))
+ value_layer = self.transpose_for_scores(self.value(current_states))
+ if past_key_value is not None and not is_cross_attention:
+ key_layer = torch.cat([past_key_value[0], key_layer], dim=2)
+ value_layer = torch.cat([past_key_value[1], value_layer], dim=2)
+
+ if self.is_decoder:
+ # if cross_attention save Tuple(torch.Tensor, torch.Tensor) of all cross attention key/value_states.
+ # Further calls to cross_attention layer can then reuse all cross-attention
+ # key/value_states (first "if" case)
+ # if uni-directional self-attention (decoder) save Tuple(torch.Tensor, torch.Tensor) of
+ # all previous decoder key/value_states. Further calls to uni-directional self-attention
+ # can concat previous decoder key/value_states to current projected key/value_states (third "elif" case)
+ # if encoder bi-directional self-attention `past_key_value` is always `None`
+ past_key_value = (key_layer, value_layer)
+
+ # SDPA with memory-efficient backend is broken in torch==2.1.2 when using non-contiguous inputs and a custom
+ # attn_mask, so we need to call `.contiguous()` here. This was fixed in torch==2.2.0.
+ # Reference: https://github.com/pytorch/pytorch/issues/112577
+ if self.require_contiguous_qkv and query_layer.device.type == "cuda" and attention_mask is not None:
+ query_layer = query_layer.contiguous()
+ key_layer = key_layer.contiguous()
+ value_layer = value_layer.contiguous()
+
+ # We dispatch to SDPA's Flash Attention or Efficient kernels via this `is_causal` if statement instead of an inline conditional assignment
+ # in SDPA to support both torch.compile's dynamic shapes and full graph options. An inline conditional prevents dynamic shapes from compiling.
+ # The tgt_len > 1 is necessary to match with AttentionMaskConverter.to_causal_4d that does not create
+ # a causal mask in case tgt_len == 1.
+ is_causal = (
+ True if self.is_decoder and not is_cross_attention and attention_mask is None and tgt_len > 1 else False
+ )
+
+ attn_output = torch.nn.functional.scaled_dot_product_attention(
+ query_layer,
+ key_layer,
+ value_layer,
+ attn_mask=attention_mask,
+ dropout_p=self.dropout_prob if self.training else 0.0,
+ is_causal=is_causal,
+ )
+
+ attn_output = attn_output.transpose(1, 2)
+ attn_output = attn_output.reshape(bsz, tgt_len, self.all_head_size)
+
+ outputs = (attn_output,)
+ if self.is_decoder:
+ outputs = outputs + (past_key_value,)
+ return outputs
+
+
+class RobertaSelfOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states + input_tensor)
+ return hidden_states
+
+
+ROBERTA_SELF_ATTENTION_CLASSES = {
+ "eager": RobertaSelfAttention,
+ "sdpa": RobertaSdpaSelfAttention,
+}
+
+
+class RobertaAttention(nn.Module):
+ def __init__(self, config, position_embedding_type=None):
+ super().__init__()
+ self.self = ROBERTA_SELF_ATTENTION_CLASSES[config._attn_implementation](
+ config, position_embedding_type=position_embedding_type
+ )
+ self.output = RobertaSelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.self.num_attention_heads, self.self.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.self.query = prune_linear_layer(self.self.query, index)
+ self.self.key = prune_linear_layer(self.self.key, index)
+ self.self.value = prune_linear_layer(self.self.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.self.num_attention_heads = self.self.num_attention_heads - len(heads)
+ self.self.all_head_size = self.self.attention_head_size * self.self.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ past_key_value: Optional[Tuple[Tuple[torch.FloatTensor]]] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.Tensor]:
+ self_outputs = self.self(
+ hidden_states,
+ attention_mask,
+ head_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ past_key_value,
+ output_attentions,
+ )
+ attention_output = self.output(self_outputs[0], hidden_states)
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+
+class RobertaIntermediate(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+class RobertaOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states + input_tensor)
+ return hidden_states
+
+
+class RobertaLayer(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = RobertaAttention(config)
+ self.is_decoder = config.is_decoder
+ self.add_cross_attention = config.add_cross_attention
+ if self.add_cross_attention:
+ if not self.is_decoder:
+ raise ValueError(f"{self} should be used as a decoder model if cross attention is added")
+ self.crossattention = RobertaAttention(config, position_embedding_type="absolute")
+ self.intermediate = RobertaIntermediate(config)
+ self.output = RobertaOutput(config)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ past_key_value: Optional[Tuple[Tuple[torch.FloatTensor]]] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> Tuple[torch.Tensor]:
+ # decoder uni-directional self-attention cached key/values tuple is at positions 1,2
+ self_attn_past_key_value = past_key_value[:2] if past_key_value is not None else None
+ self_attention_outputs = self.attention(
+ hidden_states,
+ attention_mask,
+ head_mask,
+ output_attentions=output_attentions,
+ past_key_value=self_attn_past_key_value,
+ )
+ attention_output = self_attention_outputs[0]
+
+ # if decoder, the last output is tuple of self-attn cache
+ if self.is_decoder:
+ outputs = self_attention_outputs[1:-1]
+ present_key_value = self_attention_outputs[-1]
+ else:
+ outputs = self_attention_outputs[1:] # add self attentions if we output attention weights
+
+ cross_attn_present_key_value = None
+ if self.is_decoder and encoder_hidden_states is not None:
+ if not hasattr(self, "crossattention"):
+ raise ValueError(
+ f"If `encoder_hidden_states` are passed, {self} has to be instantiated with cross-attention layers"
+ " by setting `config.add_cross_attention=True`"
+ )
+
+ # cross_attn cached key/values tuple is at positions 3,4 of past_key_value tuple
+ cross_attn_past_key_value = past_key_value[-2:] if past_key_value is not None else None
+ cross_attention_outputs = self.crossattention(
+ attention_output,
+ attention_mask,
+ head_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ cross_attn_past_key_value,
+ output_attentions,
+ )
+ attention_output = cross_attention_outputs[0]
+ outputs = outputs + cross_attention_outputs[1:-1] # add cross attentions if we output attention weights
+
+ # add cross-attn cache to positions 3,4 of present_key_value tuple
+ cross_attn_present_key_value = cross_attention_outputs[-1]
+ present_key_value = present_key_value + cross_attn_present_key_value
+
+ layer_output = apply_chunking_to_forward(
+ self.feed_forward_chunk, self.chunk_size_feed_forward, self.seq_len_dim, attention_output
+ )
+ outputs = (layer_output,) + outputs
+
+ # if decoder, return the attn key/values as the last output
+ if self.is_decoder:
+ outputs = outputs + (present_key_value,)
+
+ return outputs
+
+ def feed_forward_chunk(self, attention_output):
+ intermediate_output = self.intermediate(attention_output)
+ layer_output = self.output(intermediate_output, attention_output)
+ return layer_output
+
+
+class RobertaEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([RobertaLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ past_key_values: Optional[Tuple[Tuple[torch.FloatTensor]]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = False,
+ output_hidden_states: Optional[bool] = False,
+ return_dict: Optional[bool] = True,
+ ) -> Union[Tuple[torch.Tensor], BaseModelOutputWithPastAndCrossAttentions]:
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+ all_cross_attentions = () if output_attentions and self.config.add_cross_attention else None
+
+ if self.gradient_checkpointing and self.training:
+ if use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..."
+ )
+ use_cache = False
+
+ next_decoder_cache = () if use_cache else None
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+ past_key_value = past_key_values[i] if past_key_values is not None else None
+
+ if self.gradient_checkpointing and self.training:
+ layer_outputs = self._gradient_checkpointing_func(
+ layer_module.__call__,
+ hidden_states,
+ attention_mask,
+ layer_head_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ past_key_value,
+ output_attentions,
+ )
+ else:
+ layer_outputs = layer_module(
+ hidden_states,
+ attention_mask,
+ layer_head_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ past_key_value,
+ output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+ if use_cache:
+ next_decoder_cache += (layer_outputs[-1],)
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+ if self.config.add_cross_attention:
+ all_cross_attentions = all_cross_attentions + (layer_outputs[2],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [
+ hidden_states,
+ next_decoder_cache,
+ all_hidden_states,
+ all_self_attentions,
+ all_cross_attentions,
+ ]
+ if v is not None
+ )
+ return BaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=next_decoder_cache,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ cross_attentions=all_cross_attentions,
+ )
+
+
+class RobertaPooler(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.activation = nn.Tanh()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(first_token_tensor)
+ pooled_output = self.activation(pooled_output)
+ return pooled_output
+
+
+def load_tf_weights_in_roberta(model, config, tf_checkpoint_path):
+ """Load tf checkpoints in a pytorch model."""
+ try:
+ import re
+
+ import numpy as np
+ import tensorflow as tf
+ except ImportError:
+ logger.error(
+ "Loading a TensorFlow model in PyTorch, requires TensorFlow to be installed. Please see "
+ "https://www.tensorflow.org/install/ for installation instructions."
+ )
+ raise
+ tf_path = os.path.abspath(tf_checkpoint_path)
+ logger.info(f"Converting TensorFlow checkpoint from {tf_path}")
+ # Load weights from TF model
+ init_vars = tf.train.list_variables(tf_path)
+ names = []
+ arrays = []
+ for name, shape in init_vars:
+ logger.info(f"Loading TF weight {name} with shape {shape}")
+ array = tf.train.load_variable(tf_path, name)
+ names.append(name)
+ arrays.append(array)
+
+ for name, array in zip(names, arrays):
+ name = name.split("/")
+ # adam_v and adam_m are variables used in AdamWeightDecayOptimizer to calculated m and v
+ # which are not required for using pretrained model
+ if any(
+ n in ["adam_v", "adam_m", "AdamWeightDecayOptimizer", "AdamWeightDecayOptimizer_1", "global_step"]
+ for n in name
+ ):
+ logger.info(f"Skipping {'/'.join(name)}")
+ continue
+ pointer = model
+ for m_name in name:
+ if re.fullmatch(r"[A-Za-z]+_\d+", m_name):
+ scope_names = re.split(r"_(\d+)", m_name)
+ else:
+ scope_names = [m_name]
+ if scope_names[0] == "kernel" or scope_names[0] == "gamma":
+ pointer = getattr(pointer, "weight")
+ elif scope_names[0] == "output_bias" or scope_names[0] == "beta":
+ pointer = getattr(pointer, "bias")
+ elif scope_names[0] == "output_weights":
+ pointer = getattr(pointer, "weight")
+ elif scope_names[0] == "squad":
+ pointer = getattr(pointer, "classifier")
+ else:
+ try:
+ pointer = getattr(pointer, scope_names[0])
+ except AttributeError:
+ logger.info(f"Skipping {'/'.join(name)}")
+ continue
+ if len(scope_names) >= 2:
+ num = int(scope_names[1])
+ pointer = pointer[num]
+ if m_name[-11:] == "_embeddings":
+ pointer = getattr(pointer, "weight")
+ elif m_name == "kernel":
+ array = np.transpose(array)
+ try:
+ if pointer.shape != array.shape:
+ raise ValueError(f"Pointer shape {pointer.shape} and array shape {array.shape} mismatched")
+ except ValueError as e:
+ e.args += (pointer.shape, array.shape)
+ raise
+ logger.info(f"Initialize PyTorch weight {name}")
+ pointer.data = torch.from_numpy(array)
+ return model
+
+
+class RobertaPreTrainedModel(PreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = RobertaConfig
+ load_tf_weights = load_tf_weights_in_roberta
+ base_model_prefix = "roberta"
+ supports_gradient_checkpointing = True
+ _supports_sdpa = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, nn.Linear):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+
+
+ROBERTA_START_DOCSTRING = r"""
+
+ This model inherits from [`PreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) subclass.
+ Use it as a regular PyTorch Module and refer to the PyTorch documentation for all matter related to general usage
+ and behavior.
+
+ Parameters:
+ config ([`RobertaConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+ROBERTA_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`torch.LongTensor` of shape `({0})`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`torch.FloatTensor` of shape `({0})`or `(batch_size, sequence_length, target_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ token_type_ids (`torch.LongTensor` of shape `({0})`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`torch.LongTensor` of shape `({0})`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ head_mask (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ inputs_embeds (`torch.FloatTensor` of shape `({0}, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+
+@add_start_docstrings(
+ "The bare Roberta Model transformer outputting raw hidden-states without any specific head on top.",
+ ROBERTA_START_DOCSTRING,
+)
+class RobertaModel(RobertaPreTrainedModel):
+ """
+
+ The model can behave as an encoder (with only self-attention) as well as a decoder, in which case a layer of
+ cross-attention is added between the self-attention layers, following the architecture described in [Attention is
+ all you need](https://arxiv.org/abs/1706.03762) by Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit,
+ Llion Jones, Aidan N. Gomez, Lukasz Kaiser and Illia Polosukhin.
+
+ To behave as an decoder the model needs to be initialized with the `is_decoder` argument of the configuration set
+ to `True`. To be used in a Seq2Seq model, the model needs to initialized with both `is_decoder` argument and
+ `add_cross_attention` set to `True`; an `encoder_hidden_states` is then expected as an input to the forward pass.
+ """
+
+ _no_split_modules = ["RobertaEmbeddings", "RobertaLayer"]
+
+ def __init__(self, config, add_pooling_layer=True):
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = RobertaEmbeddings(config)
+ self.encoder = RobertaEncoder(config)
+
+ self.pooler = RobertaPooler(config) if add_pooling_layer else None
+
+ self.attn_implementation = config._attn_implementation
+ self.position_embedding_type = config.position_embedding_type
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.word_embeddings
+
+ def set_input_embeddings(self, value):
+ self.embeddings.word_embeddings = value
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @add_start_docstrings_to_model_forward(ROBERTA_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=BaseModelOutputWithPoolingAndCrossAttentions,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[List[torch.FloatTensor]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[Tuple[torch.Tensor], BaseModelOutputWithPoolingAndCrossAttentions]:
+ r"""
+ encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention if
+ the model is configured as a decoder.
+ encoder_attention_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length)` or `(batch_size, sequence_length, target_length)`, *optional*):
+ Mask to avoid performing attention on the padding token indices of the encoder input. This mask is used in
+ the cross-attention if the model is configured as a decoder. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+ past_key_values (`tuple(tuple(torch.FloatTensor))` of length `config.n_layers` with each tuple having 4 tensors of shape `(batch_size, num_heads, sequence_length - 1, embed_size_per_head)`):
+ Contains precomputed key and value hidden states of the attention blocks. Can be used to speed up decoding.
+
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those that
+ don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of all
+ `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see
+ `past_key_values`).
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if self.config.is_decoder:
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ else:
+ use_cache = False
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask)
+ input_shape = input_ids.size()
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ batch_size, seq_length = input_shape
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ # past_key_values_length
+ past_key_values_length = past_key_values[0][0].shape[2] if past_key_values is not None else 0
+
+ if token_type_ids is None:
+ if hasattr(self.embeddings, "token_type_ids"):
+ buffered_token_type_ids = self.embeddings.token_type_ids[:, :seq_length]
+ buffered_token_type_ids_expanded = buffered_token_type_ids.expand(batch_size, seq_length)
+ token_type_ids = buffered_token_type_ids_expanded
+ else:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=device)
+
+ embedding_output = self.embeddings(
+ input_ids=input_ids,
+ position_ids=position_ids,
+ token_type_ids=token_type_ids,
+ inputs_embeds=inputs_embeds,
+ past_key_values_length=past_key_values_length,
+ )
+
+ if attention_mask is None:
+ attention_mask = torch.ones((batch_size, seq_length + past_key_values_length), device=device)
+
+ use_sdpa_attention_masks = (
+ self.attn_implementation == "sdpa"
+ and self.position_embedding_type == "absolute"
+ and head_mask is None
+ and not output_attentions
+ )
+
+ # Expand the attention mask
+ if use_sdpa_attention_masks and attention_mask.dim() == 2:
+ # Expand the attention mask for SDPA.
+ # [bsz, seq_len] -> [bsz, 1, seq_len, seq_len]
+ if self.config.is_decoder:
+ extended_attention_mask = _prepare_4d_causal_attention_mask_for_sdpa(
+ attention_mask,
+ input_shape,
+ embedding_output,
+ past_key_values_length,
+ )
+ else:
+ extended_attention_mask = _prepare_4d_attention_mask_for_sdpa(
+ attention_mask, embedding_output.dtype, tgt_len=seq_length
+ )
+ else:
+ # We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length]
+ # ourselves in which case we just need to make it broadcastable to all heads.
+ extended_attention_mask = self.get_extended_attention_mask(attention_mask, input_shape)
+
+ # If a 2D or 3D attention mask is provided for the cross-attention
+ # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length]
+ if self.config.is_decoder and encoder_hidden_states is not None:
+ encoder_batch_size, encoder_sequence_length, _ = encoder_hidden_states.size()
+ encoder_hidden_shape = (encoder_batch_size, encoder_sequence_length)
+ if encoder_attention_mask is None:
+ encoder_attention_mask = torch.ones(encoder_hidden_shape, device=device)
+
+ if use_sdpa_attention_masks and encoder_attention_mask.dim() == 2:
+ # Expand the attention mask for SDPA.
+ # [bsz, seq_len] -> [bsz, 1, seq_len, seq_len]
+ encoder_extended_attention_mask = _prepare_4d_attention_mask_for_sdpa(
+ encoder_attention_mask, embedding_output.dtype, tgt_len=seq_length
+ )
+ else:
+ encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask)
+ else:
+ encoder_extended_attention_mask = None
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ encoder_outputs = self.encoder(
+ embedding_output,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_extended_attention_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = encoder_outputs[0]
+ pooled_output = self.pooler(sequence_output) if self.pooler is not None else None
+
+ if not return_dict:
+ return (sequence_output, pooled_output) + encoder_outputs[1:]
+
+ return BaseModelOutputWithPoolingAndCrossAttentions(
+ last_hidden_state=sequence_output,
+ pooler_output=pooled_output,
+ past_key_values=encoder_outputs.past_key_values,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ cross_attentions=encoder_outputs.cross_attentions,
+ )
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_super.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_super.py
new file mode 100644
index 0000000000000000000000000000000000000000..1f5aa55c46909efbfa5163d818956fd1dbd1bd59
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modeling_super.py
@@ -0,0 +1,632 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from examples/modular-transformers/modular_super.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_super.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+from typing import Callable, List, Optional, Tuple, Union
+
+import torch
+from torch import nn
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, StaticCache
+from ...modeling_attn_mask_utils import AttentionMaskConverter
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_outputs import BaseModelOutputWithPast
+from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import add_start_docstrings, add_start_docstrings_to_model_forward, logging
+from .configuration_super import SuperConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class SuperRMSNorm(nn.Module):
+ def __init__(self, hidden_size, eps=1e-6):
+ """
+ SuperRMSNorm is equivalent to T5LayerNorm
+ """
+ super().__init__()
+ self.weight = nn.Parameter(torch.ones(hidden_size))
+ self.variance_epsilon = eps
+
+ def forward(self, hidden_states):
+ input_dtype = hidden_states.dtype
+ hidden_states = hidden_states.to(torch.float32)
+ variance = hidden_states.pow(2).mean(-1, keepdim=True)
+ hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon)
+ return self.weight * hidden_states.to(input_dtype)
+
+ def extra_repr(self):
+ return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}"
+
+
+class SuperRotaryEmbedding(nn.Module):
+ def __init__(
+ self,
+ config: SuperConfig,
+ device=None,
+ ):
+ super().__init__()
+ self.rope_kwargs = {}
+ # BC: "rope_type" was originally "type"
+ if hasattr(config, "rope_scaling") and config.rope_scaling is not None:
+ self.rope_type = config.rope_scaling.get("rope_type", config.rope_scaling.get("type"))
+ else:
+ self.rope_type = "default"
+ self.max_seq_len_cached = config.max_position_embeddings
+ self.original_max_seq_len = config.max_position_embeddings
+
+ self.config = config
+ self.rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type]
+
+ inv_freq, self.attention_scaling = self.rope_init_fn(self.config, device, **self.rope_kwargs)
+ self.register_buffer("inv_freq", inv_freq, persistent=False)
+ self.original_inv_freq = self.inv_freq
+
+ def _dynamic_frequency_update(self, position_ids, device):
+ """
+ dynamic RoPE layers should recompute `inv_freq` in the following situations:
+ 1 - growing beyond the cached sequence length (allow scaling)
+ 2 - the current sequence length is in the original scale (avoid losing precision with small sequences)
+ """
+ seq_len = torch.max(position_ids) + 1
+ if seq_len > self.max_seq_len_cached: # growth
+ inv_freq, self.attention_scaling = self.rope_init_fn(
+ self.config, device, seq_len=seq_len, **self.rope_kwargs
+ )
+ self.register_buffer("inv_freq", inv_freq, persistent=False) # TODO joao: may break with compilation
+ self.max_seq_len_cached = seq_len
+
+ if seq_len < self.original_max_seq_len and self.max_seq_len_cached > self.original_max_seq_len: # reset
+ self.register_buffer("inv_freq", self.original_inv_freq, persistent=False)
+ self.max_seq_len_cached = self.original_max_seq_len
+
+ @torch.no_grad()
+ def forward(self, x, position_ids):
+ if "dynamic" in self.rope_type:
+ self._dynamic_frequency_update(position_ids, device=x.device)
+
+ # Core RoPE block
+ inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1)
+ position_ids_expanded = position_ids[:, None, :].float()
+ # Force float32 (see https://github.com/huggingface/transformers/pull/29285)
+ device_type = x.device.type
+ device_type = device_type if isinstance(device_type, str) and device_type != "mps" else "cpu"
+ with torch.autocast(device_type=device_type, enabled=False):
+ freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2)
+ emb = torch.cat((freqs, freqs), dim=-1)
+ cos = emb.cos()
+ sin = emb.sin()
+
+ # Advanced RoPE types (e.g. yarn) apply a post-processing scaling factor, equivalent to scaling attention
+ cos = cos * self.attention_scaling
+ sin = sin * self.attention_scaling
+
+ return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype)
+
+
+class SuperMLP(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.hidden_size = config.hidden_size
+ self.intermediate_size = config.intermediate_size
+ self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=config.mlp_bias)
+ self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=config.mlp_bias)
+ self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=config.mlp_bias)
+ self.act_fn = ACT2FN[config.hidden_act]
+
+ def forward(self, x):
+ down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x))
+ return down_proj
+
+
+def rotate_half(x):
+ """Rotates half the hidden dims of the input."""
+ x1 = x[..., : x.shape[-1] // 2]
+ x2 = x[..., x.shape[-1] // 2 :]
+ return torch.cat((-x2, x1), dim=-1)
+
+
+def apply_rotary_pos_emb(q, k, cos, sin, position_ids=None, unsqueeze_dim=1):
+ """Applies Rotary Position Embedding to the query and key tensors.
+
+ Args:
+ q (`torch.Tensor`): The query tensor.
+ k (`torch.Tensor`): The key tensor.
+ cos (`torch.Tensor`): The cosine part of the rotary embedding.
+ sin (`torch.Tensor`): The sine part of the rotary embedding.
+ position_ids (`torch.Tensor`, *optional*):
+ Deprecated and unused.
+ unsqueeze_dim (`int`, *optional*, defaults to 1):
+ The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and
+ sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note
+ that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and
+ k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes
+ cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have
+ the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2.
+ Returns:
+ `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding.
+ """
+ cos = cos.unsqueeze(unsqueeze_dim)
+ sin = sin.unsqueeze(unsqueeze_dim)
+ q_embed = (q * cos) + (rotate_half(q) * sin)
+ k_embed = (k * cos) + (rotate_half(k) * sin)
+ return q_embed, k_embed
+
+
+def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor:
+ """
+ This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch,
+ num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim)
+ """
+ batch, num_key_value_heads, slen, head_dim = hidden_states.shape
+ if n_rep == 1:
+ return hidden_states
+ hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim)
+ return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim)
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ key_states = repeat_kv(key, module.num_key_value_groups)
+ value_states = repeat_kv(value, module.num_key_value_groups)
+
+ attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling
+ if attention_mask is not None:
+ causal_mask = attention_mask[:, :, :, : key_states.shape[-2]]
+ attn_weights = attn_weights + causal_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value_states)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class SuperAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config: SuperConfig, layer_idx: int):
+ super().__init__()
+ self.config = config
+ self.layer_idx = layer_idx
+ self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads)
+ self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads
+ self.scaling = self.head_dim**-0.5
+ self.attention_dropout = config.attention_dropout
+ self.is_causal = True
+
+ self.q_proj = nn.Linear(
+ config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.k_proj = nn.Linear(
+ config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.v_proj = nn.Linear(
+ config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.o_proj = nn.Linear(
+ config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_bias
+ )
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ position_embeddings: Tuple[torch.Tensor, torch.Tensor],
+ attention_mask: Optional[torch.Tensor],
+ past_key_value: Optional[Cache] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> Tuple[torch.Tensor, Optional[torch.Tensor], Optional[Tuple[torch.Tensor]]]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+
+ query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ cos, sin = position_embeddings
+ query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin)
+
+ if past_key_value is not None:
+ # sin and cos are specific to RoPE models; cache_position needed for the static cache
+ cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position}
+ key_states, value_states = past_key_value.update(key_states, value_states, self.layer_idx, cache_kwargs)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ if self.config._attn_implementation == "sdpa" and kwargs.get("output_attentions", False):
+ logger.warning_once(
+ "`torch.nn.functional.scaled_dot_product_attention` does not support `output_attentions=True`. Falling back to "
+ 'eager attention. This warning can be removed using the argument `attn_implementation="eager"` when loading the model.'
+ )
+ else:
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.attention_dropout,
+ scaling=self.scaling,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ return attn_output, attn_weights
+
+
+class SuperDecoderLayer(nn.Module):
+ def __init__(self, config: SuperConfig, layer_idx: int):
+ super().__init__()
+ self.hidden_size = config.hidden_size
+
+ self.self_attn = SuperAttention(config=config, layer_idx=layer_idx)
+
+ self.mlp = SuperMLP(config)
+ self.input_layernorm = SuperRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.post_attention_layernorm = SuperRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_value: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = False,
+ cache_position: Optional[torch.LongTensor] = None,
+ position_embeddings: Optional[Tuple[torch.Tensor, torch.Tensor]] = None, # necessary, but kept here for BC
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> Tuple[torch.FloatTensor, Optional[Tuple[torch.FloatTensor, torch.FloatTensor]]]:
+ residual = hidden_states
+
+ hidden_states = self.input_layernorm(hidden_states)
+
+ # Self Attention
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_value=past_key_value,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ position_embeddings=position_embeddings,
+ **kwargs,
+ )
+ hidden_states = residual + hidden_states
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.post_attention_layernorm(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+ if output_attentions:
+ outputs += (self_attn_weights,)
+
+ return outputs
+
+
+SUPER_START_DOCSTRING = r"""
+ This model inherits from [`PreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) subclass.
+ Use it as a regular PyTorch Module and refer to the PyTorch documentation for all matter related to general usage
+ and behavior.
+
+ Parameters:
+ config ([`SuperConfig`]):
+ Model configuration class with all the parameters of the model. Initializing with a config file does not
+ load the weights associated with the model, only the configuration. Check out the
+ [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+
+@add_start_docstrings(
+ "The bare Super Model outputting raw hidden-states without any specific head on top.",
+ SUPER_START_DOCSTRING,
+)
+class SuperPreTrainedModel(PreTrainedModel):
+ config_class = SuperConfig
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["SuperDecoderLayer"]
+ _skip_keys_device_placement = ["past_key_values"]
+ _supports_flash_attn_2 = True
+ _supports_sdpa = True
+ _supports_cache_class = True
+ _supports_quantized_cache = True
+ _supports_static_cache = True
+
+ def _init_weights(self, module):
+ std = self.config.initializer_range
+ if isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+
+
+SUPER_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you provide
+ it.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ If `past_key_values` is used, optionally only the last `input_ids` have to be input (see
+ `past_key_values`).
+
+ If you want to change padding behavior, you should read [`modeling_opt._prepare_decoder_attention_mask`]
+ and modify to your needs. See diagram 1 in [the paper](https://arxiv.org/abs/1910.13461) for more
+ information on the default strategy.
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ position_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.n_positions - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ past_key_values (`Cache` or `tuple(tuple(torch.FloatTensor))`, *optional*):
+ Pre-computed hidden-states (key and values in the self-attention blocks and in the cross-attention
+ blocks) that can be used to speed up sequential decoding. This typically consists in the `past_key_values`
+ returned by the model at a previous stage of decoding, when `use_cache=True` or `config.use_cache=True`.
+
+ Two formats are allowed:
+ - a [`~cache_utils.Cache`] instance, see our
+ [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache);
+ - Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of
+ shape `(batch_size, num_heads, sequence_length, embed_size_per_head)`). This is also known as the legacy
+ cache format.
+
+ The model will output the same cache format that is fed as input. If no `past_key_values` are passed, the
+ legacy cache format will be returned.
+
+ If `past_key_values` are used, the user can optionally input only the last `input_ids` (those that don't
+ have their past key value states given to this model) of shape `(batch_size, 1)` instead of all `input_ids`
+ of shape `(batch_size, sequence_length)`.
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see
+ `past_key_values`).
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*):
+ Indices depicting the position of the input sequence tokens in the sequence. Contrarily to `position_ids`,
+ this tensor is not affected by padding. It is used to update the cache in the correct position and to infer
+ the complete sequence length.
+"""
+
+
+@add_start_docstrings(
+ "The bare Super Model outputting raw hidden-states without any specific head on top.",
+ SUPER_START_DOCSTRING,
+)
+class SuperModel(SuperPreTrainedModel):
+ """
+ Transformer decoder consisting of *config.num_hidden_layers* layers. Each layer is a [`SuperDecoderLayer`]
+
+ Args:
+ config: SuperConfig
+ """
+
+ def __init__(self, config: SuperConfig):
+ super().__init__(config)
+ self.padding_idx = config.pad_token_id
+ self.vocab_size = config.vocab_size
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx)
+ self.layers = nn.ModuleList(
+ [SuperDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)]
+ )
+ self.norm = SuperRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.rotary_emb = SuperRotaryEmbedding(config=config)
+ self.gradient_checkpointing = False
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embed_tokens
+
+ def set_input_embeddings(self, value):
+ self.embed_tokens = value
+
+ @add_start_docstrings_to_model_forward(SUPER_INPUTS_DOCSTRING)
+ def forward(
+ self,
+ input_ids: torch.LongTensor = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Union[Cache, List[torch.FloatTensor]]] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[Tuple, BaseModelOutputWithPast]:
+ out = super().forward(
+ input_ids,
+ attention_mask,
+ position_ids,
+ past_key_values,
+ inputs_embeds,
+ use_cache,
+ output_attentions,
+ output_hidden_states,
+ return_dict,
+ cache_position,
+ )
+ out.logits *= 2**4
+ return out
+
+ def _update_causal_mask(
+ self,
+ attention_mask: torch.Tensor,
+ input_tensor: torch.Tensor,
+ cache_position: torch.Tensor,
+ past_key_values: Cache,
+ output_attentions: bool,
+ ):
+ if self.config._attn_implementation == "flash_attention_2":
+ if attention_mask is not None and (attention_mask == 0.0).any():
+ return attention_mask
+ return None
+
+ # For SDPA, when possible, we will rely on its `is_causal` argument instead of its `attn_mask` argument, in
+ # order to dispatch on Flash Attention 2. This feature is not compatible with static cache, as SDPA will fail
+ # to infer the attention mask.
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ using_static_cache = isinstance(past_key_values, StaticCache)
+
+ # When output attentions is True, sdpa implementation's forward method calls the eager implementation's forward
+ if self.config._attn_implementation == "sdpa" and not using_static_cache and not output_attentions:
+ if AttentionMaskConverter._ignore_causal_mask_sdpa(
+ attention_mask,
+ inputs_embeds=input_tensor,
+ past_key_values_length=past_seen_tokens,
+ is_training=self.training,
+ ):
+ return None
+
+ dtype, device = input_tensor.dtype, input_tensor.device
+ sequence_length = input_tensor.shape[1]
+ if using_static_cache:
+ target_length = past_key_values.get_max_cache_shape()
+ else:
+ target_length = (
+ attention_mask.shape[-1]
+ if isinstance(attention_mask, torch.Tensor)
+ else past_seen_tokens + sequence_length + 1
+ )
+
+ # In case the provided `attention` mask is 2D, we generate a causal mask here (4D).
+ causal_mask = self._prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask,
+ sequence_length=sequence_length,
+ target_length=target_length,
+ dtype=dtype,
+ device=device,
+ cache_position=cache_position,
+ batch_size=input_tensor.shape[0],
+ )
+
+ if (
+ self.config._attn_implementation == "sdpa"
+ and attention_mask is not None
+ and attention_mask.device.type == "cuda"
+ and not output_attentions
+ ):
+ # Attend to all tokens in fully masked rows in the causal_mask, for example the relevant first rows when
+ # using left padding. This is required by F.scaled_dot_product_attention memory-efficient attention path.
+ # Details: https://github.com/pytorch/pytorch/issues/110213
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = AttentionMaskConverter._unmask_unattended(causal_mask, min_dtype)
+
+ return causal_mask
+
+ @staticmethod
+ def _prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask: torch.Tensor,
+ sequence_length: int,
+ target_length: int,
+ dtype: torch.dtype,
+ device: torch.device,
+ cache_position: torch.Tensor,
+ batch_size: int,
+ **kwargs,
+ ):
+ """
+ Creates a causal 4D mask of shape `(batch_size, 1, query_length, key_value_length)` from a 2D mask of shape
+ `(batch_size, key_value_length)`, or if the input `attention_mask` is already 4D, do nothing.
+
+ Args:
+ attention_mask (`torch.Tensor`):
+ A 2D attention mask of shape `(batch_size, key_value_length)` or a 4D attention mask of shape
+ `(batch_size, 1, query_length, key_value_length)`.
+ sequence_length (`int`):
+ The sequence length being processed.
+ target_length (`int`):
+ The target length: when generating with static cache, the mask should be as long as the static cache,
+ to account for the 0 padding, the part of the cache that is not filled yet.
+ dtype (`torch.dtype`):
+ The dtype to use for the 4D attention mask.
+ device (`torch.device`):
+ The device to plcae the 4D attention mask on.
+ cache_position (`torch.Tensor`):
+ Indices depicting the position of the input sequence tokens in the sequence.
+ batch_size (`torch.Tensor`):
+ Batch size.
+ """
+ if attention_mask is not None and attention_mask.dim() == 4:
+ # In this case we assume that the mask comes already in inverted form and requires no inversion or slicing.
+ causal_mask = attention_mask
+ else:
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = torch.full(
+ (sequence_length, target_length), fill_value=min_dtype, dtype=dtype, device=device
+ )
+ if sequence_length != 1:
+ causal_mask = torch.triu(causal_mask, diagonal=1)
+ causal_mask *= torch.arange(target_length, device=device) > cache_position.reshape(-1, 1)
+ causal_mask = causal_mask[None, None, :, :].expand(batch_size, 1, -1, -1)
+ if attention_mask is not None:
+ causal_mask = causal_mask.clone() # copy to contiguous memory for in-place edit
+ mask_length = attention_mask.shape[-1]
+ padding_mask = causal_mask[:, :, :, :mask_length] + attention_mask[:, None, None, :]
+ padding_mask = padding_mask == 0
+ causal_mask[:, :, :, :mask_length] = causal_mask[:, :, :, :mask_length].masked_fill(
+ padding_mask, min_dtype
+ )
+
+ return causal_mask
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_dummy.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_dummy.py
new file mode 100644
index 0000000000000000000000000000000000000000..fb64ba4d8566655604001f44bea2ed34363b7d3b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_dummy.py
@@ -0,0 +1,15 @@
+import torch
+
+from transformers.models.llama.modeling_llama import LlamaModel
+
+
+def rotate_half(x):
+ """Rotates half the hidden dims of the input."""
+ x1 = x[..., : x.shape[-1] // 4]
+ x2 = x[..., x.shape[-1] // 4 :]
+ return torch.cat((-x2, x1), dim=-1)
+
+
+# example where we need some deps and some functions
+class DummyModel(LlamaModel):
+ pass
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_dummy_bert.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_dummy_bert.py
new file mode 100644
index 0000000000000000000000000000000000000000..7a83a2e0ed2fc238d564749fe91ba30dd8a19c2d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_dummy_bert.py
@@ -0,0 +1,27 @@
+from typing import List, Optional, Tuple, Union
+
+import torch
+
+from transformers.models.bert.modeling_bert import BertModel
+
+from ...modeling_outputs import BaseModelOutputWithPoolingAndCrossAttentions
+
+
+class DummyBertModel(BertModel):
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[List[torch.FloatTensor]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[Tuple[torch.Tensor], BaseModelOutputWithPoolingAndCrossAttentions]:
+ return super().forward(input_ids)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_from_uppercase_model.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_from_uppercase_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..ef3044e7ee2cf023f0d23fed2ea4da678f06b98d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_from_uppercase_model.py
@@ -0,0 +1,6 @@
+from transformers.models.clip.modeling_clip import CLIPEncoderLayer
+
+
+# Check if we can correctly grab dependencies with correct naming from all UPPERCASE old model
+class FromUppercaseModelEncoderLayer(CLIPEncoderLayer):
+ pass
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_multimodal1.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_multimodal1.py
new file mode 100644
index 0000000000000000000000000000000000000000..8f8eaf91a371065beff347e9b5f1c7f58f1b614b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_multimodal1.py
@@ -0,0 +1,6 @@
+from transformers.models.llama.modeling_llama import LlamaModel
+
+
+# Check that we can correctly change the prefix (here add Text part at the end of the name)
+class Multimodal1TextModel(LlamaModel):
+ pass
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_multimodal2.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_multimodal2.py
new file mode 100644
index 0000000000000000000000000000000000000000..bc11e0b2869fb9ab758347f49ee145560120dafb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_multimodal2.py
@@ -0,0 +1,88 @@
+"""
+Here, because clip is not consistent with the use of the "Text" and "Vision" prefixes, we cannot simply use
+```
+class Multimodal2VisionModel(CLIPVisionModel):
+ pass
+```
+with the hope that all dependencies will be renamed as `Multimodal2VisionClass`. For this reason, if we want consistency and
+use the "Vision" part everywhere, we need to overwrite the intermediate classes and add the prefix everytime.
+This adds noise to the modular, but is unfortunately unavoidable.
+"""
+
+from torch import nn
+
+from transformers.models.clip.modeling_clip import (
+ CLIPMLP,
+ CLIPAttention,
+ CLIPEncoder,
+ CLIPEncoderLayer,
+ CLIPFlashAttention2,
+ CLIPPreTrainedModel,
+ CLIPSdpaAttention,
+ CLIPVisionModel,
+ CLIPVisionTransformer,
+)
+from transformers.utils import add_start_docstrings
+
+
+class Multimodal2VisionAttention(CLIPAttention):
+ pass
+
+
+# Check that adding the second base class correctly set the parent, even though in clip it does not have the "Vision" part
+class Multimodal2VisionSdpaAttention(CLIPSdpaAttention, Multimodal2VisionAttention):
+ pass
+
+
+# Check that adding the second base class correctly set the parent, even though in clip it does not have the "Vision" part
+class Multimodal2VisionFlashAttention2(CLIPFlashAttention2, Multimodal2VisionAttention):
+ pass
+
+
+MULTIMODAL2_VISION_ATTENTION_CLASSES = {
+ "eager": Multimodal2VisionAttention,
+ "sdpa": Multimodal2VisionSdpaAttention,
+ "flash_attention_2": Multimodal2VisionFlashAttention2,
+}
+
+
+class Multimodal2VisionMLP(CLIPMLP):
+ pass
+
+
+class Multimodal2VisionEncoderLayer(CLIPEncoderLayer):
+ def __init__(self, config):
+ super().__init__()
+ self.self_attn = MULTIMODAL2_VISION_ATTENTION_CLASSES[config._attn_implementation](config)
+ self.mlp = Multimodal2VisionMLP(config)
+
+
+class Multimodal2VisionEncoder(CLIPEncoder):
+ def __init__(self, config):
+ super().__init__(config)
+ self.layers = nn.ModuleList([Multimodal2VisionEncoderLayer(config) for _ in range(config.num_hidden_layers)])
+
+
+# Finally here the `Vision` part was correct in CLIP, but we still need to tell it that the encoder arg should use it as well
+class Multimodal2VisionTransformer(CLIPVisionTransformer):
+ def __init__(self, config):
+ super().__init__(config)
+ self.encoder = Multimodal2VisionEncoder(config)
+
+
+class Multimodal2VisionPreTrainedModel(CLIPPreTrainedModel):
+ def _init_weights(self, module):
+ if isinstance(module, Multimodal2VisionMLP):
+ pass
+
+
+MULTIMODAL2_VISION_START_DOCSTRING = "doc"
+
+
+# Here the only arg `self.vision_model = CLIPVisionTransformer(config)` in CLIPVisionModel already has the "Vision" part, so
+# no need to overwrite it, it will look for `Multimodal2VisionTransformer` which has already being redefined above
+# Note: we may want to redefine decorator as well for full consistency, as CLIP does not use "CLIP_VISION_START_DOCSTRING" but only
+# "CLIP_START_DOCSTRING"
+@add_start_docstrings("New doc", MULTIMODAL2_VISION_START_DOCSTRING)
+class Multimodal2VisionModel(CLIPVisionModel, Multimodal2VisionPreTrainedModel):
+ _no_split_modules = ["Multimodal2VisionEncoderLayer"]
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_my_new_model.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_my_new_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..c1ea8b0a72490b19412ed909c045660ddc5dc015
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_my_new_model.py
@@ -0,0 +1,15 @@
+from transformers.models.llama.configuration_llama import LlamaConfig
+
+
+# Example where we only want to only add a new config argument and new arg doc
+# here there is no `ARG` so we are gonna take parent doc
+class MyNewModelConfig(LlamaConfig):
+ r"""
+ new_param (`int`, *optional*, defaults to `False`):
+ A fun new parameter
+ """
+
+ def __init__(self, mlp_bias=True, new_param=0, **super_kwargs):
+ super().__init__(self, **super_kwargs)
+ self.mlp_bias = mlp_bias
+ self.new_param = new_param
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_my_new_model2.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_my_new_model2.py
new file mode 100644
index 0000000000000000000000000000000000000000..2e449e06b16225a9dd45ab7c1ce81cb918404780
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_my_new_model2.py
@@ -0,0 +1,31 @@
+from transformers.models.gemma.modeling_gemma import GemmaForSequenceClassification
+from transformers.models.llama.configuration_llama import LlamaConfig
+
+
+# Example where we only want to only modify the docstring
+class MyNewModel2Config(LlamaConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`GemmaModel`]. It is used to instantiate an Gemma
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the Gemma-7B.
+ e.g. [google/gemma-7b](https://huggingface.co/google/gemma-7b)
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+ Args:
+ vocab_size (`int`, *optional*, defaults to 256000):
+ Vocabulary size of the Gemma model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`GemmaModel`]
+ ```python
+ >>> from transformers import GemmaModel, GemmaConfig
+ >>> # Initializing a Gemma gemma-7b style configuration
+ >>> configuration = GemmaConfig()
+ >>> # Initializing a model from the gemma-7b style configuration
+ >>> model = GemmaModel(configuration)
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+
+# Example where alllllll the dependencies are fetched to just copy the entire class
+class MyNewModel2ForSequenceClassification(GemmaForSequenceClassification):
+ pass
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_new_imgproc_model.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_new_imgproc_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..1d054166c28d3e546dad4ca70b09372121dd318a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_new_imgproc_model.py
@@ -0,0 +1,9 @@
+import torch
+import torch.utils.checkpoint
+
+from transformers.models.blip.image_processing_blip import BlipImageProcessor
+
+
+class ImgprocModelImageProcessor(BlipImageProcessor):
+ def new_image_processing_method(self, pixel_values: torch.FloatTensor):
+ return pixel_values / 2
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_new_model.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_new_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..166c7955c1b5a91839a5b72ecdfb5c4b48660813
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_new_model.py
@@ -0,0 +1,35 @@
+# Example where we only want to overwrite the defaults of an init
+
+from transformers.models.gemma.configuration_gemma import GemmaConfig
+
+
+class NewModelConfig(GemmaConfig):
+ def __init__(
+ self,
+ vocab_size=256030,
+ hidden_size=64,
+ intermediate_size=90,
+ num_hidden_layers=28,
+ num_attention_heads=16,
+ num_key_value_heads=16,
+ head_dim=256,
+ hidden_act="gelu_pytorch_tanh",
+ hidden_activation=None,
+ max_position_embeddings=1500,
+ initializer_range=0.02,
+ rms_norm_eps=1e-6,
+ use_cache=True,
+ pad_token_id=0,
+ eos_token_id=1,
+ bos_token_id=2,
+ tie_word_embeddings=True,
+ rope_theta=10000.0,
+ attention_bias=False,
+ attention_dropout=0.0,
+ **kwargs,
+ ):
+ super().__init__(self, **kwargs)
+
+ @property
+ def num_heads(self):
+ return self.num_attention_heads
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_new_task_model.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_new_task_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..877fba00a50ff4417a8a41f527b75258f268109f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_new_task_model.py
@@ -0,0 +1,84 @@
+from typing import ClassVar, List, Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from transformers.models.paligemma.modeling_paligemma import PaliGemmaForConditionalGeneration
+
+from ...cache_utils import Cache
+
+
+class NewTaskModelForNewTask(PaliGemmaForConditionalGeneration):
+ main_input_name: ClassVar[str] = "doc_input_ids" # transformers-related
+
+ def __init__(self, config):
+ super().__init__(config=config)
+
+ self.embedding_dim = self.config.embedding_dim
+ self.custom_text_proj = nn.Linear(self.config.text_config.hidden_size, self.embedding_dim)
+
+ if self.language_model._tied_weights_keys is not None:
+ self._tied_weights_keys = [f"model.language_model.{k}" for k in self.language_model._tied_weights_keys]
+
+ self.post_init()
+
+ def forward(
+ self,
+ input_ids: torch.LongTensor = None,
+ pixel_values: torch.FloatTensor = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Union[List[torch.FloatTensor], Cache]] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ num_logits_to_keep: int = 0,
+ ):
+ r"""
+ Returns:
+ """
+ vlm_outputs = super().forward(
+ input_ids=input_ids,
+ pixel_values=pixel_values,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ token_type_ids=token_type_ids,
+ cache_position=cache_position,
+ inputs_embeds=inputs_embeds,
+ labels=labels,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=True,
+ return_dict=True,
+ num_logits_to_keep=num_logits_to_keep,
+ )
+ last_hidden_states = vlm_outputs.hidden_states[-1] # (batch_size, sequence_length, hidden_size)
+ proj = self.custom_text_proj(last_hidden_states) # (batch_size, sequence_length, dim)
+
+ # L2 normalization
+ embeddings = proj / proj.norm(dim=-1, keepdim=True) # (batch_size, sequence_length, dim)
+
+ embeddings = embeddings * attention_mask.unsqueeze(-1) # (batch_size, sequence_length, dim)
+
+ return (embeddings,) + vlm_outputs
+
+ def resize_token_embeddings(
+ self,
+ new_num_tokens: Optional[int] = None,
+ pad_to_multiple_of=None,
+ ) -> nn.Embedding:
+ model_embeds = self.language_model.resize_token_embeddings(new_num_tokens, pad_to_multiple_of)
+
+ # Update vocab size
+ self.config.text_config.vocab_size = model_embeds.num_embeddings
+ self.config.vocab_size = model_embeds.num_embeddings
+ self.vocab_size = model_embeds.num_embeddings
+
+ return model_embeds
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_roberta.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_roberta.py
new file mode 100644
index 0000000000000000000000000000000000000000..13dca4845c132b1e735bcc34d2df2b81111cc97d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_roberta.py
@@ -0,0 +1,17 @@
+import torch.nn as nn
+
+from transformers.models.bert.modeling_bert import BertEmbeddings, BertModel
+
+
+class RobertaEmbeddings(BertEmbeddings):
+ def __init__(self, config):
+ super().__init__(config)
+ self.pad_token_id = config.pad_token_id
+ self.position_embeddings = nn.Embedding(
+ config.max_position_embeddings, config.hidden_size, config.pad_token_id
+ )
+
+
+class RobertaModel(BertModel):
+ def __init__(self, config, add_pooling_layer=True):
+ super().__init__(self, config)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_super.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_super.py
new file mode 100644
index 0000000000000000000000000000000000000000..59909a41e4dcc6452a060c8b2414f2faccae07b3
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/modular-transformers/modular_super.py
@@ -0,0 +1,39 @@
+from typing import List, Optional, Tuple, Union
+
+import torch
+
+from transformers.modeling_outputs import CausalLMOutputWithPast
+from transformers.models.llama.modeling_llama import LlamaModel
+
+from ...cache_utils import Cache
+
+
+# example where we need some deps and some functions
+class SuperModel(LlamaModel):
+ def forward(
+ self,
+ input_ids: torch.LongTensor = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Union[Cache, List[torch.FloatTensor]]] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[Tuple, CausalLMOutputWithPast]:
+ out = super().forward(
+ input_ids,
+ attention_mask,
+ position_ids,
+ past_key_values,
+ inputs_embeds,
+ use_cache,
+ output_attentions,
+ output_hidden_states,
+ return_dict,
+ cache_position,
+ )
+ out.logits *= 2**4
+ return out
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..4e318b3edb920c6c1d01fa332be596e4de87bd96
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/README.md
@@ -0,0 +1,381 @@
+
+
+# Examples
+
+This folder contains actively maintained examples of use of 🤗 Transformers using the PyTorch backend, organized by ML task.
+
+## The Big Table of Tasks
+
+Here is the list of all our examples:
+- with information on whether they are **built on top of `Trainer`** (if not, they still work, they might
+ just lack some features),
+- whether or not they have a version using the [🤗 Accelerate](https://github.com/huggingface/accelerate) library.
+- whether or not they leverage the [🤗 Datasets](https://github.com/huggingface/datasets) library.
+- links to **Colab notebooks** to walk through the scripts and run them easily,
+
+
+| Task | Example datasets | Trainer support | 🤗 Accelerate | 🤗 Datasets | Colab
+|---|---|:---:|:---:|:---:|:---:|
+| [**`language-modeling`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/language-modeling) | [WikiText-2](https://huggingface.co/datasets/wikitext) | ✅ | ✅ | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)
+| [**`multiple-choice`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/multiple-choice) | [SWAG](https://huggingface.co/datasets/swag) | ✅ | ✅ | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice.ipynb)
+| [**`question-answering`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering) | [SQuAD](https://huggingface.co/datasets/squad) | ✅ | ✅ | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb)
+| [**`summarization`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization) | [XSum](https://huggingface.co/datasets/xsum) | ✅ | ✅ | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization.ipynb)
+| [**`text-classification`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-classification) | [GLUE](https://huggingface.co/datasets/glue) | ✅ | ✅ | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification.ipynb)
+| [**`text-generation`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-generation) | - | n/a | - | - | [](https://colab.research.google.com/github/huggingface/blog/blob/main/notebooks/02_how_to_generate.ipynb)
+| [**`token-classification`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/token-classification) | [CoNLL NER](https://huggingface.co/datasets/conll2003) | ✅ |✅ | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification.ipynb)
+| [**`translation`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/translation) | [WMT](https://huggingface.co/datasets/wmt17) | ✅ | ✅ |✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation.ipynb)
+| [**`speech-recognition`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/speech-recognition) | [TIMIT](https://huggingface.co/datasets/timit_asr) | ✅ | - |✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/speech_recognition.ipynb)
+| [**`multi-lingual speech-recognition`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/speech-recognition) | [Common Voice](https://huggingface.co/datasets/common_voice) | ✅ | - |✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multi_lingual_speech_recognition.ipynb)
+| [**`audio-classification`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/audio-classification) | [SUPERB KS](https://huggingface.co/datasets/superb) | ✅ | - |✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/audio_classification.ipynb)
+| [**`image-pretraining`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining) | [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k) | ✅ | - |✅ | /
+| [**`image-classification`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) | [CIFAR-10](https://huggingface.co/datasets/cifar10) | ✅ | ✅ |✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb)
+| [**`semantic-segmentation`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/semantic-segmentation) | [SCENE_PARSE_150](https://huggingface.co/datasets/scene_parse_150) | ✅ | ✅ |✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/semantic_segmentation.ipynb)
+| [**`object-detection`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/object-detection) | [CPPE-5](https://huggingface.co/datasets/cppe-5) | ✅ | ✅ |✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/transformers_doc/en/pytorch/object_detection.ipynb)
+| [**`instance-segmentation`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/instance-segmentation) | [ADE20K sample](https://huggingface.co/datasets/qubvel-hf/ade20k-mini) | ✅ | ✅ |✅ |
+
+
+## Running quick tests
+
+Most examples are equipped with a mechanism to truncate the number of dataset samples to the desired length. This is useful for debugging purposes, for example to quickly check that all stages of the programs can complete, before running the same setup on the full dataset which may take hours to complete.
+
+For example here is how to truncate all three splits to just 50 samples each:
+```bash
+examples/pytorch/token-classification/run_ner.py \
+--max_train_samples 50 \
+--max_eval_samples 50 \
+--max_predict_samples 50 \
+[...]
+```
+
+Most example scripts should have the first two command line arguments and some have the third one. You can quickly check if a given example supports any of these by passing a `-h` option, e.g.:
+```bash
+examples/pytorch/token-classification/run_ner.py -h
+```
+
+## Resuming training
+
+You can resume training from a previous checkpoint like this:
+
+1. Pass `--output_dir previous_output_dir` without `--overwrite_output_dir` to resume training from the latest checkpoint in `output_dir` (what you would use if the training was interrupted, for instance).
+2. Pass `--resume_from_checkpoint path_to_a_specific_checkpoint` to resume training from that checkpoint folder.
+
+Should you want to turn an example into a notebook where you'd no longer have access to the command
+line, 🤗 Trainer supports resuming from a checkpoint via `trainer.train(resume_from_checkpoint)`.
+
+1. If `resume_from_checkpoint` is `True` it will look for the last checkpoint in the value of `output_dir` passed via `TrainingArguments`.
+2. If `resume_from_checkpoint` is a path to a specific checkpoint it will use that saved checkpoint folder to resume the training from.
+
+
+### Upload the trained/fine-tuned model to the Hub
+
+All the example scripts support automatic upload of your final model to the [Model Hub](https://huggingface.co/models) by adding a `--push_to_hub` argument. It will then create a repository with your username slash the name of the folder you are using as `output_dir`. For instance, `"sgugger/test-mrpc"` if your username is `sgugger` and you are working in the folder `~/tmp/test-mrpc`.
+
+To specify a given repository name, use the `--hub_model_id` argument. You will need to specify the whole repository name (including your username), for instance `--hub_model_id sgugger/finetuned-bert-mrpc`. To upload to an organization you are a member of, just use the name of that organization instead of your username: `--hub_model_id huggingface/finetuned-bert-mrpc`.
+
+A few notes on this integration:
+
+- you will need to be logged in to the Hugging Face website locally for it to work, the easiest way to achieve this is to run `huggingface-cli login` and then type your username and password when prompted. You can also pass along your authentication token with the `--hub_token` argument.
+- the `output_dir` you pick will either need to be a new folder or a local clone of the distant repository you are using.
+
+## Distributed training and mixed precision
+
+All the PyTorch scripts mentioned above work out of the box with distributed training and mixed precision, thanks to
+the [Trainer API](https://huggingface.co/transformers/main_classes/trainer.html). To launch one of them on _n_ GPUs,
+use the following command:
+
+```bash
+torchrun \
+ --nproc_per_node number_of_gpu_you_have path_to_script.py \
+ --all_arguments_of_the_script
+```
+
+As an example, here is how you would fine-tune the BERT large model (with whole word masking) on the text
+classification MNLI task using the `run_glue` script, with 8 GPUs:
+
+```bash
+torchrun \
+ --nproc_per_node 8 pytorch/text-classification/run_glue.py \
+ --model_name_or_path google-bert/bert-large-uncased-whole-word-masking \
+ --task_name mnli \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 8 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3.0 \
+ --output_dir /tmp/mnli_output/
+```
+
+If you have a GPU with mixed precision capabilities (architecture Pascal or more recent), you can use mixed precision
+training with PyTorch 1.6.0 or latest, or by installing the [Apex](https://github.com/NVIDIA/apex) library for previous
+versions. Just add the flag `--fp16` to your command launching one of the scripts mentioned above!
+
+Using mixed precision training usually results in 2x-speedup for training with the same final results (as shown in
+[this table](https://github.com/huggingface/transformers/tree/main/examples/text-classification#mixed-precision-training)
+for text classification).
+
+## Running on TPUs
+
+When using Tensorflow, TPUs are supported out of the box as a `tf.distribute.Strategy`.
+
+When using PyTorch, we support TPUs thanks to `pytorch/xla`. For more context and information on how to setup your TPU environment refer to Google's documentation and to the
+very detailed [pytorch/xla README](https://github.com/pytorch/xla/blob/master/README.md).
+
+In this repo, we provide a very simple launcher script named
+[xla_spawn.py](https://github.com/huggingface/transformers/tree/main/examples/pytorch/xla_spawn.py) that lets you run our
+example scripts on multiple TPU cores without any boilerplate. Just pass a `--num_cores` flag to this script, then your
+regular training script with its arguments (this is similar to the `torch.distributed.launch` helper for
+`torch.distributed`):
+
+```bash
+python xla_spawn.py --num_cores num_tpu_you_have \
+ path_to_script.py \
+ --all_arguments_of_the_script
+```
+
+As an example, here is how you would fine-tune the BERT large model (with whole word masking) on the text
+classification MNLI task using the `run_glue` script, with 8 TPUs (from this folder):
+
+```bash
+python xla_spawn.py --num_cores 8 \
+ text-classification/run_glue.py \
+ --model_name_or_path google-bert/bert-large-uncased-whole-word-masking \
+ --task_name mnli \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 8 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3.0 \
+ --output_dir /tmp/mnli_output/
+```
+
+## Using Accelerate
+
+Most PyTorch example scripts have a version using the [🤗 Accelerate](https://github.com/huggingface/accelerate) library
+that exposes the training loop so it's easy for you to customize or tweak them to your needs. They all require you to
+install `accelerate` with the latest development version
+
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+Then you can easily launch any of the scripts by running
+
+```bash
+accelerate config
+```
+
+and reply to the questions asked. Then
+
+```bash
+accelerate test
+```
+
+that will check everything is ready for training. Finally, you can launch training with
+
+```bash
+accelerate launch path_to_script.py --args_to_script
+```
+
+## Logging & Experiment tracking
+
+You can easily log and monitor your runs code. The following are currently supported:
+
+* [TensorBoard](https://www.tensorflow.org/tensorboard)
+* [Weights & Biases](https://docs.wandb.ai/integrations/huggingface)
+* [Comet ML](https://www.comet.com/docs/v2/integrations/ml-frameworks/transformers/)
+* [Neptune](https://docs.neptune.ai/integrations-and-supported-tools/model-training/hugging-face)
+* [ClearML](https://clear.ml/docs/latest/docs/getting_started/ds/ds_first_steps)
+* [DVCLive](https://dvc.org/doc/dvclive/ml-frameworks/huggingface)
+
+### Weights & Biases
+
+To use Weights & Biases, install the wandb package with:
+
+```bash
+pip install wandb
+```
+
+Then log in the command line:
+
+```bash
+wandb login
+```
+
+If you are in Jupyter or Colab, you should login with:
+
+```python
+import wandb
+wandb.login()
+```
+
+To enable logging to W&B, include `"wandb"` in the `report_to` of your `TrainingArguments` or script. Or just pass along `--report_to_all` if you have `wandb` installed.
+
+Whenever you use the `Trainer` class, your losses, evaluation metrics, model topology and gradients will automatically be logged.
+
+Advanced configuration is possible by setting environment variables:
+
+| Environment Variable | Value |
+|---|---|
+| WANDB_LOG_MODEL | Log the model as artifact (log the model as artifact at the end of training) (`false` by default) |
+| WANDB_WATCH | one of `gradients` (default) to log histograms of gradients, `all` to log histograms of both gradients and parameters, or `false` for no histogram logging |
+| WANDB_PROJECT | Organize runs by project |
+
+Set run names with `run_name` argument present in scripts or as part of `TrainingArguments`.
+
+Additional configuration options are available through generic [wandb environment variables](https://docs.wandb.com/library/environment-variables).
+
+Refer to related [documentation & examples](https://docs.wandb.ai/integrations/huggingface).
+
+### Comet
+
+To use `comet_ml`, install the Python package with:
+
+```bash
+pip install comet_ml
+```
+
+or if in a Conda environment:
+
+```bash
+conda install -c comet_ml -c anaconda -c conda-forge comet_ml
+```
+
+### Neptune
+
+First, install the Neptune client library. You can do it with either `pip` or `conda`:
+
+`pip`:
+
+```bash
+pip install neptune
+```
+
+`conda`:
+
+```bash
+conda install -c conda-forge neptune
+```
+
+Next, in your model training script, import `NeptuneCallback`:
+
+```python
+from transformers.integrations import NeptuneCallback
+```
+
+To enable Neptune logging, in your `TrainingArguments`, set the `report_to` argument to `"neptune"`:
+
+```python
+training_args = TrainingArguments(
+ "quick-training-distilbert-mrpc",
+ eval_strategy="steps",
+ eval_steps=20,
+ report_to="neptune",
+)
+
+trainer = Trainer(
+ model,
+ training_args,
+ ...
+)
+```
+
+**Note:** This method requires saving your Neptune credentials as environment variables (see the bottom of the section).
+
+Alternatively, for more logging options, create a Neptune callback:
+
+```python
+neptune_callback = NeptuneCallback()
+```
+
+To add more detail to the tracked run, you can supply optional arguments to `NeptuneCallback`.
+
+Some examples:
+
+```python
+neptune_callback = NeptuneCallback(
+ name = "DistilBERT",
+ description = "DistilBERT fine-tuned on GLUE/MRPC",
+ tags = ["args-callback", "fine-tune", "MRPC"], # tags help you manage runs in Neptune
+ base_namespace="callback", # the default is "finetuning"
+ log_checkpoints = "best", # other options are "last", "same", and None
+ capture_hardware_metrics = False, # additional keyword arguments for a Neptune run
+)
+```
+
+Pass the callback to the Trainer:
+
+```python
+training_args = TrainingArguments(..., report_to=None)
+trainer = Trainer(
+ model,
+ training_args,
+ ...
+ callbacks=[neptune_callback],
+)
+```
+
+Now, when you start the training with `trainer.train()`, your metadata will be logged in Neptune.
+
+**Note:** Although you can pass your **Neptune API token** and **project name** as arguments when creating the callback, the recommended way is to save them as environment variables:
+
+| Environment variable | Value |
+| :------------------- | :--------------------------------------------------- |
+| `NEPTUNE_API_TOKEN` | Your Neptune API token. To find and copy it, click your Neptune avatar and select **Get your API token**. |
+| `NEPTUNE_PROJECT` | The full name of your Neptune project (`workspace-name/project-name`). To find and copy it, head to **project settings** → **Properties**. |
+
+For detailed instructions and examples, see the [Neptune docs](https://docs.neptune.ai/integrations/transformers/).
+
+### ClearML
+
+To use ClearML, install the clearml package with:
+
+```bash
+pip install clearml
+```
+
+Then [create new credentials]() from the ClearML Server. You can get a free hosted server [here]() or [self-host your own]()!
+After creating your new credentials, you can either copy the local snippet which you can paste after running:
+
+```bash
+clearml-init
+```
+
+Or you can copy the jupyter snippet if you are in Jupyter or Colab:
+
+```python
+%env CLEARML_WEB_HOST=https://app.clear.ml
+%env CLEARML_API_HOST=https://api.clear.ml
+%env CLEARML_FILES_HOST=https://files.clear.ml
+%env CLEARML_API_ACCESS_KEY=***
+%env CLEARML_API_SECRET_KEY=***
+```
+
+
+To enable logging to ClearML, include `"clearml"` in the `report_to` of your `TrainingArguments` or script. Or just pass along `--report_to all` if you have `clearml` already installed.
+
+Advanced configuration is possible by setting environment variables:
+
+| Environment Variable | Value |
+|---|---|
+| CLEARML_PROJECT | Name of the project in ClearML. (default: `"HuggingFace Transformers"`) |
+| CLEARML_TASK | Name of the task in ClearML. (default: `"Trainer"`) |
+
+Additional configuration options are available through generic [clearml environment variables](https://clear.ml/docs/latest/docs/configs/env_vars).
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/_tests_requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/_tests_requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..fb86259116d4e915d3b9a5c14ce95ffa165779dd
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/_tests_requirements.txt
@@ -0,0 +1,32 @@
+tensorboard
+scikit-learn
+seqeval
+psutil
+sacrebleu >= 1.4.12
+git+https://github.com/huggingface/accelerate@main#egg=accelerate
+rouge-score
+tensorflow_datasets
+matplotlib
+git-python==1.0.3
+faiss-cpu
+streamlit
+elasticsearch
+nltk
+pandas
+datasets >= 1.13.3
+fire
+pytest<8.0.1
+conllu
+sentencepiece != 0.1.92
+protobuf
+torch
+torchvision
+torchaudio
+jiwer
+librosa
+evaluate >= 0.2.0
+timm
+albumentations >= 1.4.16
+torchmetrics
+pycocotools
+Pillow>=10.0.1,<=15.0
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/audio-classification/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/audio-classification/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..bc4581089c3fd2eaa9eb7d8489966d3acfe00686
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/audio-classification/README.md
@@ -0,0 +1,148 @@
+
+
+# Audio classification examples
+
+The following examples showcase how to fine-tune `Wav2Vec2` for audio classification using PyTorch.
+
+Speech recognition models that have been pretrained in unsupervised fashion on audio data alone,
+*e.g.* [Wav2Vec2](https://huggingface.co/transformers/main/model_doc/wav2vec2.html),
+[HuBERT](https://huggingface.co/transformers/main/model_doc/hubert.html),
+[XLSR-Wav2Vec2](https://huggingface.co/transformers/main/model_doc/xlsr_wav2vec2.html), have shown to require only
+very little annotated data to yield good performance on speech classification datasets.
+
+## Single-GPU
+
+The following command shows how to fine-tune [wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base) on the 🗣️ [Keyword Spotting subset](https://huggingface.co/datasets/superb#ks) of the SUPERB dataset.
+
+```bash
+python run_audio_classification.py \
+ --model_name_or_path facebook/wav2vec2-base \
+ --dataset_name superb \
+ --dataset_config_name ks \
+ --output_dir wav2vec2-base-ft-keyword-spotting \
+ --overwrite_output_dir \
+ --remove_unused_columns False \
+ --do_train \
+ --do_eval \
+ --fp16 \
+ --learning_rate 3e-5 \
+ --max_length_seconds 1 \
+ --attention_mask False \
+ --warmup_ratio 0.1 \
+ --num_train_epochs 5 \
+ --per_device_train_batch_size 32 \
+ --gradient_accumulation_steps 4 \
+ --per_device_eval_batch_size 32 \
+ --dataloader_num_workers 4 \
+ --logging_strategy steps \
+ --logging_steps 10 \
+ --eval_strategy epoch \
+ --save_strategy epoch \
+ --load_best_model_at_end True \
+ --metric_for_best_model accuracy \
+ --save_total_limit 3 \
+ --seed 0 \
+ --push_to_hub
+```
+
+On a single V100 GPU (16GB), this script should run in ~14 minutes and yield accuracy of **98.26%**.
+
+👀 See the results here: [anton-l/wav2vec2-base-ft-keyword-spotting](https://huggingface.co/anton-l/wav2vec2-base-ft-keyword-spotting)
+
+> If your model classification head dimensions do not fit the number of labels in the dataset, you can specify `--ignore_mismatched_sizes` to adapt it.
+
+## Multi-GPU
+
+The following command shows how to fine-tune [wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base) for 🌎 **Language Identification** on the [CommonLanguage dataset](https://huggingface.co/datasets/anton-l/common_language).
+
+```bash
+python run_audio_classification.py \
+ --model_name_or_path facebook/wav2vec2-base \
+ --dataset_name common_language \
+ --audio_column_name audio \
+ --label_column_name language \
+ --output_dir wav2vec2-base-lang-id \
+ --overwrite_output_dir \
+ --remove_unused_columns False \
+ --do_train \
+ --do_eval \
+ --fp16 \
+ --learning_rate 3e-4 \
+ --max_length_seconds 16 \
+ --attention_mask False \
+ --warmup_ratio 0.1 \
+ --num_train_epochs 10 \
+ --per_device_train_batch_size 8 \
+ --gradient_accumulation_steps 4 \
+ --per_device_eval_batch_size 1 \
+ --dataloader_num_workers 8 \
+ --logging_strategy steps \
+ --logging_steps 10 \
+ --eval_strategy epoch \
+ --save_strategy epoch \
+ --load_best_model_at_end True \
+ --metric_for_best_model accuracy \
+ --save_total_limit 3 \
+ --seed 0 \
+ --push_to_hub
+```
+
+On 4 V100 GPUs (16GB), this script should run in ~1 hour and yield accuracy of **79.45%**.
+
+👀 See the results here: [anton-l/wav2vec2-base-lang-id](https://huggingface.co/anton-l/wav2vec2-base-lang-id)
+
+## Sharing your model on 🤗 Hub
+
+0. If you haven't already, [sign up](https://huggingface.co/join) for a 🤗 account
+
+1. Make sure you have `git-lfs` installed and git set up.
+
+```bash
+$ apt install git-lfs
+```
+
+2. Log in with your HuggingFace account credentials using `huggingface-cli`
+
+```bash
+$ huggingface-cli login
+# ...follow the prompts
+```
+
+3. When running the script, pass the following arguments:
+
+```bash
+python run_audio_classification.py \
+ --push_to_hub \
+ --hub_model_id \
+ ...
+```
+
+### Examples
+
+The following table shows a couple of demonstration fine-tuning runs.
+It has been verified that the script works for the following datasets:
+
+- [SUPERB Keyword Spotting](https://huggingface.co/datasets/superb#ks)
+- [Common Language](https://huggingface.co/datasets/common_language)
+
+| Dataset | Pretrained Model | # transformer layers | Accuracy on eval | GPU setup | Training time | Fine-tuned Model & Logs |
+|---------|------------------|----------------------|------------------|-----------|---------------|--------------------------|
+| Keyword Spotting | [ntu-spml/distilhubert](https://huggingface.co/ntu-spml/distilhubert) | 2 | 0.9706 | 1 V100 GPU | 11min | [here](https://huggingface.co/anton-l/distilhubert-ft-keyword-spotting) |
+| Keyword Spotting | [facebook/wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base) | 12 | 0.9826 | 1 V100 GPU | 14min | [here](https://huggingface.co/anton-l/wav2vec2-base-ft-keyword-spotting) |
+| Keyword Spotting | [facebook/hubert-base-ls960](https://huggingface.co/facebook/hubert-base-ls960) | 12 | 0.9819 | 1 V100 GPU | 14min | [here](https://huggingface.co/anton-l/hubert-base-ft-keyword-spotting) |
+| Keyword Spotting | [asapp/sew-mid-100k](https://huggingface.co/asapp/sew-mid-100k) | 24 | 0.9757 | 1 V100 GPU | 15min | [here](https://huggingface.co/anton-l/sew-mid-100k-ft-keyword-spotting) |
+| Common Language | [facebook/wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base) | 12 | 0.7945 | 4 V100 GPUs | 1h10m | [here](https://huggingface.co/anton-l/wav2vec2-base-lang-id) |
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/audio-classification/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/audio-classification/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..acf058d4cf46eaa3e7fe55012a9ecd9982a12bf3
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/audio-classification/requirements.txt
@@ -0,0 +1,5 @@
+datasets>=1.14.0
+evaluate
+librosa
+torchaudio
+torch>=1.6
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/audio-classification/run_audio_classification.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/audio-classification/run_audio_classification.py
new file mode 100644
index 0000000000000000000000000000000000000000..d9cb0187e4d82fc8fa6a3c0edb390e665df3f692
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/audio-classification/run_audio_classification.py
@@ -0,0 +1,433 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import logging
+import os
+import sys
+import warnings
+from dataclasses import dataclass, field
+from random import randint
+from typing import Optional
+
+import datasets
+import evaluate
+import numpy as np
+from datasets import DatasetDict, load_dataset
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoFeatureExtractor,
+ AutoModelForAudioClassification,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ set_seed,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+logger = logging.getLogger(__name__)
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.14.0", "To fix: pip install -r examples/pytorch/audio-classification/requirements.txt")
+
+
+def random_subsample(wav: np.ndarray, max_length: float, sample_rate: int = 16000):
+ """Randomly sample chunks of `max_length` seconds from the input audio"""
+ sample_length = int(round(sample_rate * max_length))
+ if len(wav) <= sample_length:
+ return wav
+ random_offset = randint(0, len(wav) - sample_length - 1)
+ return wav[random_offset : random_offset + sample_length]
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ Using `HfArgumentParser` we can turn this class
+ into argparse arguments to be able to specify them on
+ the command line.
+ """
+
+ dataset_name: Optional[str] = field(default=None, metadata={"help": "Name of a dataset from the datasets package"})
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_file: Optional[str] = field(
+ default=None, metadata={"help": "A file containing the training audio paths and labels."}
+ )
+ eval_file: Optional[str] = field(
+ default=None, metadata={"help": "A file containing the validation audio paths and labels."}
+ )
+ train_split_name: str = field(
+ default="train",
+ metadata={
+ "help": "The name of the training data set split to use (via the datasets library). Defaults to 'train'"
+ },
+ )
+ eval_split_name: str = field(
+ default="validation",
+ metadata={
+ "help": (
+ "The name of the training data set split to use (via the datasets library). Defaults to 'validation'"
+ )
+ },
+ )
+ audio_column_name: str = field(
+ default="audio",
+ metadata={"help": "The name of the dataset column containing the audio data. Defaults to 'audio'"},
+ )
+ label_column_name: str = field(
+ default="label", metadata={"help": "The name of the dataset column containing the labels. Defaults to 'label'"}
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_length_seconds: float = field(
+ default=20,
+ metadata={"help": "Audio clips will be randomly cut to this length during training if the value is set."},
+ )
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ default="facebook/wav2vec2-base",
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"},
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from the Hub"}
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ feature_extractor_name: Optional[str] = field(
+ default=None, metadata={"help": "Name or path of preprocessor config."}
+ )
+ freeze_feature_encoder: bool = field(
+ default=True, metadata={"help": "Whether to freeze the feature encoder layers of the model."}
+ )
+ attention_mask: bool = field(
+ default=True, metadata={"help": "Whether to generate an attention mask in the feature extractor."}
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ freeze_feature_extractor: Optional[bool] = field(
+ default=None, metadata={"help": "Whether to freeze the feature extractor layers of the model."}
+ )
+ ignore_mismatched_sizes: bool = field(
+ default=False,
+ metadata={"help": "Will enable to load a pretrained model whose head dimensions are different."},
+ )
+
+ def __post_init__(self):
+ if not self.freeze_feature_extractor and self.freeze_feature_encoder:
+ warnings.warn(
+ "The argument `--freeze_feature_extractor` is deprecated and "
+ "will be removed in a future version. Use `--freeze_feature_encoder` "
+ "instead. Setting `freeze_feature_encoder==True`.",
+ FutureWarning,
+ )
+ if self.freeze_feature_extractor and not self.freeze_feature_encoder:
+ raise ValueError(
+ "The argument `--freeze_feature_extractor` is deprecated and "
+ "should not be used in combination with `--freeze_feature_encoder`. "
+ "Only make use of `--freeze_feature_encoder`."
+ )
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_audio_classification", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to train from scratch."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Initialize our dataset and prepare it for the audio classification task.
+ raw_datasets = DatasetDict()
+ raw_datasets["train"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=data_args.train_split_name,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ raw_datasets["eval"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=data_args.eval_split_name,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ if data_args.audio_column_name not in raw_datasets["train"].column_names:
+ raise ValueError(
+ f"--audio_column_name {data_args.audio_column_name} not found in dataset '{data_args.dataset_name}'. "
+ "Make sure to set `--audio_column_name` to the correct audio column - one of "
+ f"{', '.join(raw_datasets['train'].column_names)}."
+ )
+
+ if data_args.label_column_name not in raw_datasets["train"].column_names:
+ raise ValueError(
+ f"--label_column_name {data_args.label_column_name} not found in dataset '{data_args.dataset_name}'. "
+ "Make sure to set `--label_column_name` to the correct text column - one of "
+ f"{', '.join(raw_datasets['train'].column_names)}."
+ )
+
+ # Setting `return_attention_mask=True` is the way to get a correctly masked mean-pooling over
+ # transformer outputs in the classifier, but it doesn't always lead to better accuracy
+ feature_extractor = AutoFeatureExtractor.from_pretrained(
+ model_args.feature_extractor_name or model_args.model_name_or_path,
+ return_attention_mask=model_args.attention_mask,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ # `datasets` takes care of automatically loading and resampling the audio,
+ # so we just need to set the correct target sampling rate.
+ raw_datasets = raw_datasets.cast_column(
+ data_args.audio_column_name, datasets.features.Audio(sampling_rate=feature_extractor.sampling_rate)
+ )
+
+ model_input_name = feature_extractor.model_input_names[0]
+
+ def train_transforms(batch):
+ """Apply train_transforms across a batch."""
+ subsampled_wavs = []
+ for audio in batch[data_args.audio_column_name]:
+ wav = random_subsample(
+ audio["array"], max_length=data_args.max_length_seconds, sample_rate=feature_extractor.sampling_rate
+ )
+ subsampled_wavs.append(wav)
+ inputs = feature_extractor(subsampled_wavs, sampling_rate=feature_extractor.sampling_rate)
+ output_batch = {model_input_name: inputs.get(model_input_name)}
+ output_batch["labels"] = list(batch[data_args.label_column_name])
+
+ return output_batch
+
+ def val_transforms(batch):
+ """Apply val_transforms across a batch."""
+ wavs = [audio["array"] for audio in batch[data_args.audio_column_name]]
+ inputs = feature_extractor(wavs, sampling_rate=feature_extractor.sampling_rate)
+ output_batch = {model_input_name: inputs.get(model_input_name)}
+ output_batch["labels"] = list(batch[data_args.label_column_name])
+
+ return output_batch
+
+ # Prepare label mappings.
+ # We'll include these in the model's config to get human readable labels in the Inference API.
+ labels = raw_datasets["train"].features[data_args.label_column_name].names
+ label2id, id2label = {}, {}
+ for i, label in enumerate(labels):
+ label2id[label] = str(i)
+ id2label[str(i)] = label
+
+ # Load the accuracy metric from the datasets package
+ metric = evaluate.load("accuracy", cache_dir=model_args.cache_dir)
+
+ # Define our compute_metrics function. It takes an `EvalPrediction` object (a namedtuple with
+ # `predictions` and `label_ids` fields) and has to return a dictionary string to float.
+ def compute_metrics(eval_pred):
+ """Computes accuracy on a batch of predictions"""
+ predictions = np.argmax(eval_pred.predictions, axis=1)
+ return metric.compute(predictions=predictions, references=eval_pred.label_ids)
+
+ config = AutoConfig.from_pretrained(
+ model_args.config_name or model_args.model_name_or_path,
+ num_labels=len(labels),
+ label2id=label2id,
+ id2label=id2label,
+ finetuning_task="audio-classification",
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ model = AutoModelForAudioClassification.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ ignore_mismatched_sizes=model_args.ignore_mismatched_sizes,
+ )
+
+ # freeze the convolutional waveform encoder
+ if model_args.freeze_feature_encoder:
+ model.freeze_feature_encoder()
+
+ if training_args.do_train:
+ if data_args.max_train_samples is not None:
+ raw_datasets["train"] = (
+ raw_datasets["train"].shuffle(seed=training_args.seed).select(range(data_args.max_train_samples))
+ )
+ # Set the training transforms
+ raw_datasets["train"].set_transform(train_transforms, output_all_columns=False)
+
+ if training_args.do_eval:
+ if data_args.max_eval_samples is not None:
+ raw_datasets["eval"] = (
+ raw_datasets["eval"].shuffle(seed=training_args.seed).select(range(data_args.max_eval_samples))
+ )
+ # Set the validation transforms
+ raw_datasets["eval"].set_transform(val_transforms, output_all_columns=False)
+
+ # Initialize our trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=raw_datasets["train"] if training_args.do_train else None,
+ eval_dataset=raw_datasets["eval"] if training_args.do_eval else None,
+ compute_metrics=compute_metrics,
+ processing_class=feature_extractor,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model()
+ trainer.log_metrics("train", train_result.metrics)
+ trainer.save_metrics("train", train_result.metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ metrics = trainer.evaluate()
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ # Write model card and (optionally) push to hub
+ kwargs = {
+ "finetuned_from": model_args.model_name_or_path,
+ "tasks": "audio-classification",
+ "dataset": data_args.dataset_name,
+ "tags": ["audio-classification"],
+ }
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/conftest.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/conftest.py
new file mode 100644
index 0000000000000000000000000000000000000000..70b4d4c12bc48865c2dd98316b784844db237895
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/conftest.py
@@ -0,0 +1,45 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+# tests directory-specific settings - this file is run automatically
+# by pytest before any tests are run
+
+import sys
+import warnings
+from os.path import abspath, dirname, join
+
+
+# allow having multiple repository checkouts and not needing to remember to rerun
+# `pip install -e '.[dev]'` when switching between checkouts and running tests.
+git_repo_path = abspath(join(dirname(dirname(dirname(__file__))), "src"))
+sys.path.insert(1, git_repo_path)
+
+
+# silence FutureWarning warnings in tests since often we can't act on them until
+# they become normal warnings - i.e. the tests still need to test the current functionality
+warnings.simplefilter(action="ignore", category=FutureWarning)
+
+
+def pytest_addoption(parser):
+ from transformers.testing_utils import pytest_addoption_shared
+
+ pytest_addoption_shared(parser)
+
+
+def pytest_terminal_summary(terminalreporter):
+ from transformers.testing_utils import pytest_terminal_summary_main
+
+ make_reports = terminalreporter.config.getoption("--make-reports")
+ if make_reports:
+ pytest_terminal_summary_main(terminalreporter, id=make_reports)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/contrastive-image-text/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/contrastive-image-text/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..c39f17a138a632dfa6d1c79a149a45c9584bec51
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/contrastive-image-text/README.md
@@ -0,0 +1,102 @@
+
+
+# VisionTextDualEncoder and CLIP model training examples
+
+The following example showcases how to train a CLIP-like vision-text dual encoder model
+using a pre-trained vision and text encoder.
+
+Such a model can be used for natural language image search and potentially zero-shot image classification.
+The model is inspired by [CLIP](https://openai.com/blog/clip/), introduced by Alec Radford et al.
+The idea is to train a vision encoder and a text encoder jointly to project the representation of images and their
+captions into the same embedding space, such that the caption embeddings are located near the embeddings
+of the images they describe.
+
+### Download COCO dataset (2017)
+This example uses COCO dataset (2017) through a custom dataset script, which requires users to manually download the
+COCO dataset before training.
+
+```bash
+mkdir data
+cd data
+wget http://images.cocodataset.org/zips/train2017.zip
+wget http://images.cocodataset.org/zips/val2017.zip
+wget http://images.cocodataset.org/zips/test2017.zip
+wget http://images.cocodataset.org/annotations/annotations_trainval2017.zip
+wget http://images.cocodataset.org/annotations/image_info_test2017.zip
+cd ..
+```
+
+Having downloaded COCO dataset manually you should be able to load with the `ydshieh/coc_dataset_script` dataset loading script:
+
+```py
+import os
+import datasets
+
+COCO_DIR = os.path.join(os.getcwd(), "data")
+ds = datasets.load_dataset("ydshieh/coco_dataset_script", "2017", data_dir=COCO_DIR)
+```
+
+### Create a model from a vision encoder model and a text encoder model
+Next, we create a [VisionTextDualEncoderModel](https://huggingface.co/docs/transformers/model_doc/vision-text-dual-encoder#visiontextdualencoder).
+The `VisionTextDualEncoderModel` class lets you load any vision and text encoder model to create a dual encoder.
+Here is an example of how to load the model using pre-trained vision and text models.
+
+```python3
+from transformers import (
+ VisionTextDualEncoderModel,
+ VisionTextDualEncoderProcessor,
+ AutoTokenizer,
+ AutoImageProcessor
+)
+
+model = VisionTextDualEncoderModel.from_vision_text_pretrained(
+ "openai/clip-vit-base-patch32", "FacebookAI/roberta-base"
+)
+
+tokenizer = AutoTokenizer.from_pretrained("FacebookAI/roberta-base")
+image_processor = AutoImageProcessor.from_pretrained("openai/clip-vit-base-patch32")
+processor = VisionTextDualEncoderProcessor(image_processor, tokenizer)
+
+# save the model and processor
+model.save_pretrained("clip-roberta")
+processor.save_pretrained("clip-roberta")
+```
+
+This loads both the text and vision encoders using pre-trained weights, the projection layers are randomly
+initialized except for CLIP's vision model. If you use CLIP to initialize the vision model then the vision projection weights are also
+loaded using the pre-trained weights.
+
+### Train the model
+Finally, we can run the example script to train the model:
+
+```bash
+python examples/pytorch/contrastive-image-text/run_clip.py \
+ --output_dir ./clip-roberta-finetuned \
+ --model_name_or_path ./clip-roberta \
+ --data_dir $PWD/data \
+ --dataset_name ydshieh/coco_dataset_script \
+ --dataset_config_name=2017 \
+ --image_column image_path \
+ --caption_column caption \
+ --remove_unused_columns=False \
+ --do_train --do_eval \
+ --per_device_train_batch_size="64" \
+ --per_device_eval_batch_size="64" \
+ --learning_rate="5e-5" --warmup_steps="0" --weight_decay 0.1 \
+ --overwrite_output_dir \
+ --push_to_hub
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/contrastive-image-text/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/contrastive-image-text/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..a789fee85eef5d028375e406c5ea7df85a56c738
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/contrastive-image-text/requirements.txt
@@ -0,0 +1,3 @@
+torch>=1.5.0
+torchvision>=0.6.0
+datasets>=1.8.0
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/contrastive-image-text/run_clip.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/contrastive-image-text/run_clip.py
new file mode 100644
index 0000000000000000000000000000000000000000..f8170bb416dd8c56d8f2a20b2828e9cfa21165b2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/contrastive-image-text/run_clip.py
@@ -0,0 +1,532 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2022 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Training a CLIP like dual encoder models using text and vision encoders in the library.
+
+The script can be used to train CLIP like models for languages other than English by using
+a text encoder pre-trained in the desired language. Currently this script supports the following vision
+and text models:
+Vision models: ViT(https://huggingface.co/models?filter=vit), CLIP (https://huggingface.co/models?filter=clip)
+Text models: BERT, ROBERTa (https://huggingface.co/models?filter=fill-mask)
+"""
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from typing import Optional
+
+import torch
+from datasets import load_dataset
+from PIL import Image
+from torchvision.io import ImageReadMode, read_image
+from torchvision.transforms import CenterCrop, ConvertImageDtype, Normalize, Resize
+from torchvision.transforms.functional import InterpolationMode
+
+import transformers
+from transformers import (
+ AutoImageProcessor,
+ AutoModel,
+ AutoTokenizer,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ set_seed,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+logger = logging.getLogger(__name__)
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/contrastive-image-text/requirements.txt")
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"},
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ image_processor_name: str = field(default=None, metadata={"help": "Name or path of preprocessor config."})
+ cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ freeze_vision_model: bool = field(
+ default=False, metadata={"help": "Whether to freeze the vision model parameters or not."}
+ )
+ freeze_text_model: bool = field(
+ default=False, metadata={"help": "Whether to freeze the text model parameters or not."}
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ data_dir: Optional[str] = field(default=None, metadata={"help": "The data directory containing input files."})
+ image_column: Optional[str] = field(
+ default="image_path",
+ metadata={"help": "The name of the column in the datasets containing the full image file paths."},
+ )
+ caption_column: Optional[str] = field(
+ default="caption",
+ metadata={"help": "The name of the column in the datasets containing the image captions."},
+ )
+ train_file: Optional[str] = field(
+ default=None, metadata={"help": "The input training data file (a jsonlines file)."}
+ )
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file (a jsonlines file)."},
+ )
+ max_seq_length: Optional[int] = field(
+ default=128,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+
+ def __post_init__(self):
+ if self.dataset_name is None and self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+
+
+dataset_name_mapping = {
+ "image_caption_dataset.py": ("image_path", "caption"),
+}
+
+
+# We use torchvision for faster image pre-processing. The transforms are implemented as nn.Module,
+# so we jit it to be faster.
+class Transform(torch.nn.Module):
+ def __init__(self, image_size, mean, std):
+ super().__init__()
+ self.transforms = torch.nn.Sequential(
+ Resize([image_size], interpolation=InterpolationMode.BICUBIC),
+ CenterCrop(image_size),
+ ConvertImageDtype(torch.float),
+ Normalize(mean, std),
+ )
+
+ def forward(self, x) -> torch.Tensor:
+ """`x` should be an instance of `PIL.Image.Image`"""
+ with torch.no_grad():
+ x = self.transforms(x)
+ return x
+
+
+def collate_fn(examples):
+ pixel_values = torch.stack([example["pixel_values"] for example in examples])
+ input_ids = torch.tensor([example["input_ids"] for example in examples], dtype=torch.long)
+ attention_mask = torch.tensor([example["attention_mask"] for example in examples], dtype=torch.long)
+ return {
+ "pixel_values": pixel_values,
+ "input_ids": input_ids,
+ "attention_mask": attention_mask,
+ "return_loss": True,
+ }
+
+
+def main():
+ # 1. Parse input arguments
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_clip", model_args, data_args)
+
+ # 2. Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # 3. Detecting last checkpoint and eventually continue from last checkpoint
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # 4. Load dataset
+ # Get the datasets: you can either provide your own CSV/JSON training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files this script will use the first column for the full image path and the second column for the
+ # captions (unless you specify column names for this with the `image_column` and `caption_column` arguments).
+ #
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ dataset = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ keep_in_memory=False,
+ data_dir=data_args.data_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ dataset = load_dataset(
+ extension,
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # 5. Load pretrained model, tokenizer, and image processor
+ if model_args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ elif model_args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ # Load image_processor, in this script we only use this to get the mean and std for normalization.
+ image_processor = AutoImageProcessor.from_pretrained(
+ model_args.image_processor_name or model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ model = AutoModel.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ config = model.config
+
+ def _freeze_params(module):
+ for param in module.parameters():
+ param.requires_grad = False
+
+ if model_args.freeze_vision_model:
+ _freeze_params(model.vision_model)
+
+ if model_args.freeze_text_model:
+ _freeze_params(model.text_model)
+
+ # set seed for torch dataloaders
+ set_seed(training_args.seed)
+
+ # Preprocessing the datasets.
+ # We need to tokenize inputs and targets.
+ if training_args.do_train:
+ column_names = dataset["train"].column_names
+ elif training_args.do_eval:
+ column_names = dataset["validation"].column_names
+ else:
+ logger.info("There is nothing to do. Please pass `do_train`, `do_eval` and/or `do_predict`.")
+ return
+
+ # 6. Get the column names for input/target.
+ dataset_columns = dataset_name_mapping.get(data_args.dataset_name, None)
+ if data_args.image_column is None:
+ image_column = dataset_columns[0] if dataset_columns is not None else column_names[0]
+ else:
+ image_column = data_args.image_column
+ if image_column not in column_names:
+ raise ValueError(
+ f"--image_column' value '{data_args.image_column}' needs to be one of: {', '.join(column_names)}"
+ )
+ if data_args.caption_column is None:
+ caption_column = dataset_columns[1] if dataset_columns is not None else column_names[1]
+ else:
+ caption_column = data_args.caption_column
+ if caption_column not in column_names:
+ raise ValueError(
+ f"--caption_column' value '{data_args.caption_column}' needs to be one of: {', '.join(column_names)}"
+ )
+
+ # 7. Preprocessing the datasets.
+ # Initialize torchvision transforms and jit it for faster processing.
+ image_transformations = Transform(
+ config.vision_config.image_size, image_processor.image_mean, image_processor.image_std
+ )
+ image_transformations = torch.jit.script(image_transformations)
+
+ # Preprocessing the datasets.
+ # We need to tokenize input captions and transform the images.
+ def tokenize_captions(examples):
+ captions = list(examples[caption_column])
+ text_inputs = tokenizer(captions, max_length=data_args.max_seq_length, padding="max_length", truncation=True)
+ examples["input_ids"] = text_inputs.input_ids
+ examples["attention_mask"] = text_inputs.attention_mask
+ return examples
+
+ def transform_images(examples):
+ images = [read_image(image_file, mode=ImageReadMode.RGB) for image_file in examples[image_column]]
+ examples["pixel_values"] = [image_transformations(image) for image in images]
+ return examples
+
+ def filter_corrupt_images(examples):
+ """remove problematic images"""
+ valid_images = []
+ for image_file in examples[image_column]:
+ try:
+ Image.open(image_file)
+ valid_images.append(True)
+ except Exception:
+ valid_images.append(False)
+ return valid_images
+
+ if training_args.do_train:
+ if "train" not in dataset:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = dataset["train"]
+ if data_args.max_train_samples is not None:
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+
+ train_dataset = train_dataset.filter(
+ filter_corrupt_images, batched=True, num_proc=data_args.preprocessing_num_workers
+ )
+ train_dataset = train_dataset.map(
+ function=tokenize_captions,
+ batched=True,
+ remove_columns=[col for col in column_names if col != image_column],
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on train dataset",
+ )
+
+ # Transform images on the fly as doing it on the whole dataset takes too much time.
+ train_dataset.set_transform(transform_images)
+
+ if training_args.do_eval:
+ if "validation" not in dataset:
+ raise ValueError("--do_eval requires a train validation")
+ eval_dataset = dataset["validation"]
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+
+ eval_dataset = eval_dataset.filter(
+ filter_corrupt_images, batched=True, num_proc=data_args.preprocessing_num_workers
+ )
+ eval_dataset = eval_dataset.map(
+ function=tokenize_captions,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=[col for col in column_names if col != image_column],
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on validation dataset",
+ )
+
+ # Transform images on the fly as doing it on the whole dataset takes too much time.
+ eval_dataset.set_transform(transform_images)
+
+ # 8. Initialize our trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset if training_args.do_train else None,
+ eval_dataset=eval_dataset if training_args.do_eval else None,
+ data_collator=collate_fn,
+ )
+
+ # 9. Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model()
+ tokenizer.save_pretrained(training_args.output_dir)
+ image_processor.save_pretrained(training_args.output_dir)
+ trainer.log_metrics("train", train_result.metrics)
+ trainer.save_metrics("train", train_result.metrics)
+ trainer.save_state()
+
+ # 10. Evaluation
+ if training_args.do_eval:
+ metrics = trainer.evaluate()
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ # 11. Write Training Stats and push to hub.
+ finetuned_from = model_args.model_name_or_path
+ # If from a local directory, don't set `finetuned_from` as this is required to be a valid repo. id on the Hub.
+ if os.path.isdir(finetuned_from):
+ finetuned_from = None
+ kwargs = {"finetuned_from": finetuned_from, "tasks": "contrastive-image-text-modeling"}
+ if data_args.dataset_name is not None:
+ kwargs["dataset_tags"] = data_args.dataset_name
+ if data_args.dataset_config_name is not None:
+ kwargs["dataset_args"] = data_args.dataset_config_name
+ kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
+ else:
+ kwargs["dataset"] = data_args.dataset_name
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-classification/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-classification/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..62996ee19e375ae8d802acaa1b8a02fbe5001ac5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-classification/README.md
@@ -0,0 +1,212 @@
+
+
+# Image classification examples
+
+This directory contains 2 scripts that showcase how to fine-tune any model supported by the [`AutoModelForImageClassification` API](https://huggingface.co/docs/transformers/main/en/model_doc/auto#transformers.AutoModelForImageClassification) (such as [ViT](https://huggingface.co/docs/transformers/main/en/model_doc/vit), [ConvNeXT](https://huggingface.co/docs/transformers/main/en/model_doc/convnext), [ResNet](https://huggingface.co/docs/transformers/main/en/model_doc/resnet), [Swin Transformer](https://huggingface.co/docs/transformers/main/en/model_doc/swin)...) using PyTorch. They can be used to fine-tune models on both [datasets from the hub](#using-datasets-from-hub) as well as on [your own custom data](#using-your-own-data).
+
+ \
+ --output_dir ./outputs/ \
+ --remove_unused_columns False \
+ --do_train \
+ --do_eval
+```
+
+Internally, the script will use the [`ImageFolder`](https://huggingface.co/docs/datasets/v2.0.0/en/image_process#imagefolder) feature which will automatically turn the folders into 🤗 Dataset objects.
+
+##### 💡 The above will split the train dir into training and evaluation sets
+ - To control the split amount, use the `--train_val_split` flag.
+ - To provide your own validation split in its own directory, you can pass the `--validation_dir ` flag.
+
+#### Upload your data to the hub, as a (possibly private) repo
+
+It's very easy (and convenient) to upload your image dataset to the hub using the [`ImageFolder`](https://huggingface.co/docs/datasets/v2.0.0/en/image_process#imagefolder) feature available in 🤗 Datasets. Simply do the following:
+
+```python
+from datasets import load_dataset
+
+# example 1: local folder
+dataset = load_dataset("imagefolder", data_dir="path_to_your_folder")
+
+# example 2: local files (supported formats are tar, gzip, zip, xz, rar, zstd)
+dataset = load_dataset("imagefolder", data_files="path_to_zip_file")
+
+# example 3: remote files (supported formats are tar, gzip, zip, xz, rar, zstd)
+dataset = load_dataset("imagefolder", data_files="https://download.microsoft.com/download/3/E/1/3E1C3F21-ECDB-4869-8368-6DEBA77B919F/kagglecatsanddogs_3367a.zip")
+
+# example 4: providing several splits
+dataset = load_dataset("imagefolder", data_files={"train": ["path/to/file1", "path/to/file2"], "test": ["path/to/file3", "path/to/file4"]})
+```
+
+`ImageFolder` will create a `label` column, and the label name is based on the directory name.
+
+Next, push it to the hub!
+
+```python
+# assuming you have ran the huggingface-cli login command in a terminal
+dataset.push_to_hub("name_of_your_dataset")
+
+# if you want to push to a private repo, simply pass private=True:
+dataset.push_to_hub("name_of_your_dataset", private=True)
+```
+
+and that's it! You can now train your model by simply setting the `--dataset_name` argument to the name of your dataset on the hub (as explained in [Using datasets from the 🤗 hub](#using-datasets-from-hub)).
+
+More on this can also be found in [this blog post](https://huggingface.co/blog/image-search-datasets).
+
+### Sharing your model on 🤗 Hub
+
+0. If you haven't already, [sign up](https://huggingface.co/join) for a 🤗 account
+
+1. Make sure you have `git-lfs` installed and git set up.
+
+```bash
+$ apt install git-lfs
+$ git config --global user.email "you@example.com"
+$ git config --global user.name "Your Name"
+```
+
+2. Log in with your HuggingFace account credentials using `huggingface-cli`:
+
+```bash
+$ huggingface-cli login
+# ...follow the prompts
+```
+
+3. When running the script, pass the following arguments:
+
+```bash
+python run_image_classification.py \
+ --push_to_hub \
+ --push_to_hub_model_id \
+ ...
+```
+
+## PyTorch version, no Trainer
+
+Based on the script [`run_image_classification_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/image-classification/run_image_classification_no_trainer.py).
+
+Like `run_image_classification.py`, this script allows you to fine-tune any of the models on the [hub](https://huggingface.co/models) on an image classification task. The main difference is that this script exposes the bare training loop, to allow you to quickly experiment and add any customization you would like.
+
+It offers less options than the script with `Trainer` (for instance you can easily change the options for the optimizer
+or the dataloaders directly in the script) but still run in a distributed setup, and supports mixed precision by
+the means of the [🤗 `Accelerate`](https://github.com/huggingface/accelerate) library. You can use the script normally
+after installing it:
+
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+You can then use your usual launchers to run in it in a distributed environment, but the easiest way is to run
+
+```bash
+accelerate config
+```
+
+and reply to the questions asked. Then
+
+```bash
+accelerate test
+```
+
+that will check everything is ready for training. Finally, you can launch training with
+
+```bash
+accelerate launch run_image_classification_no_trainer.py --image_column_name img
+```
+
+This command is the same and will work for:
+
+- single/multiple CPUs
+- single/multiple GPUs
+- TPUs
+
+Note that this library is in alpha release so your feedback is more than welcome if you encounter any problem using it.
+
+Regarding using custom data with this script, we refer to [using your own data](#using-your-own-data).
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-classification/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-classification/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..4926040789832ba95a79eacccba57239e5b98757
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-classification/requirements.txt
@@ -0,0 +1,5 @@
+accelerate>=0.12.0
+torch>=1.5.0
+torchvision>=0.6.0
+datasets>=2.14.0
+evaluate
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-classification/run_image_classification.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-classification/run_image_classification.py
new file mode 100644
index 0000000000000000000000000000000000000000..32d85b7d98dab1349937e2d184482e6306cd16f0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-classification/run_image_classification.py
@@ -0,0 +1,442 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from typing import Optional
+
+import evaluate
+import numpy as np
+import torch
+from datasets import load_dataset
+from PIL import Image
+from torchvision.transforms import (
+ CenterCrop,
+ Compose,
+ Lambda,
+ Normalize,
+ RandomHorizontalFlip,
+ RandomResizedCrop,
+ Resize,
+ ToTensor,
+)
+
+import transformers
+from transformers import (
+ MODEL_FOR_IMAGE_CLASSIFICATION_MAPPING,
+ AutoConfig,
+ AutoImageProcessor,
+ AutoModelForImageClassification,
+ HfArgumentParser,
+ TimmWrapperImageProcessor,
+ Trainer,
+ TrainingArguments,
+ set_seed,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+""" Fine-tuning a 🤗 Transformers model for image classification"""
+
+logger = logging.getLogger(__name__)
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/image-classification/requirements.txt")
+
+MODEL_CONFIG_CLASSES = list(MODEL_FOR_IMAGE_CLASSIFICATION_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+def pil_loader(path: str):
+ with open(path, "rb") as f:
+ im = Image.open(f)
+ return im.convert("RGB")
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ Using `HfArgumentParser` we can turn this class into argparse arguments to be able to specify
+ them on the command line.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": "Name of a dataset from the hub (could be your own, possibly private dataset hosted on the hub)."
+ },
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_dir: Optional[str] = field(default=None, metadata={"help": "A folder containing the training data."})
+ validation_dir: Optional[str] = field(default=None, metadata={"help": "A folder containing the validation data."})
+ train_val_split: Optional[float] = field(
+ default=0.15, metadata={"help": "Percent to split off of train for validation."}
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ image_column_name: str = field(
+ default="image",
+ metadata={"help": "The name of the dataset column containing the image data. Defaults to 'image'."},
+ )
+ label_column_name: str = field(
+ default="label",
+ metadata={"help": "The name of the dataset column containing the labels. Defaults to 'label'."},
+ )
+
+ def __post_init__(self):
+ if self.dataset_name is None and (self.train_dir is None and self.validation_dir is None):
+ raise ValueError(
+ "You must specify either a dataset name from the hub or a train and/or validation directory."
+ )
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ default="google/vit-base-patch16-224-in21k",
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"},
+ )
+ model_type: Optional[str] = field(
+ default=None,
+ metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ image_processor_name: str = field(default=None, metadata={"help": "Name or path of preprocessor config."})
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ ignore_mismatched_sizes: bool = field(
+ default=False,
+ metadata={"help": "Will enable to load a pretrained model whose head dimensions are different."},
+ )
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_image_classification", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Initialize our dataset and prepare it for the 'image-classification' task.
+ if data_args.dataset_name is not None:
+ dataset = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if data_args.train_dir is not None:
+ data_files["train"] = os.path.join(data_args.train_dir, "**")
+ if data_args.validation_dir is not None:
+ data_files["validation"] = os.path.join(data_args.validation_dir, "**")
+ dataset = load_dataset(
+ "imagefolder",
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ )
+
+ dataset_column_names = dataset["train"].column_names if "train" in dataset else dataset["validation"].column_names
+ if data_args.image_column_name not in dataset_column_names:
+ raise ValueError(
+ f"--image_column_name {data_args.image_column_name} not found in dataset '{data_args.dataset_name}'. "
+ "Make sure to set `--image_column_name` to the correct audio column - one of "
+ f"{', '.join(dataset_column_names)}."
+ )
+ if data_args.label_column_name not in dataset_column_names:
+ raise ValueError(
+ f"--label_column_name {data_args.label_column_name} not found in dataset '{data_args.dataset_name}'. "
+ "Make sure to set `--label_column_name` to the correct text column - one of "
+ f"{', '.join(dataset_column_names)}."
+ )
+
+ def collate_fn(examples):
+ pixel_values = torch.stack([example["pixel_values"] for example in examples])
+ labels = torch.tensor([example[data_args.label_column_name] for example in examples])
+ return {"pixel_values": pixel_values, "labels": labels}
+
+ # If we don't have a validation split, split off a percentage of train as validation.
+ data_args.train_val_split = None if "validation" in dataset.keys() else data_args.train_val_split
+ if isinstance(data_args.train_val_split, float) and data_args.train_val_split > 0.0:
+ split = dataset["train"].train_test_split(data_args.train_val_split)
+ dataset["train"] = split["train"]
+ dataset["validation"] = split["test"]
+
+ # Prepare label mappings.
+ # We'll include these in the model's config to get human readable labels in the Inference API.
+ labels = dataset["train"].features[data_args.label_column_name].names
+ label2id, id2label = {}, {}
+ for i, label in enumerate(labels):
+ label2id[label] = str(i)
+ id2label[str(i)] = label
+
+ # Load the accuracy metric from the datasets package
+ metric = evaluate.load("accuracy", cache_dir=model_args.cache_dir)
+
+ # Define our compute_metrics function. It takes an `EvalPrediction` object (a namedtuple with a
+ # predictions and label_ids field) and has to return a dictionary string to float.
+ def compute_metrics(p):
+ """Computes accuracy on a batch of predictions"""
+ return metric.compute(predictions=np.argmax(p.predictions, axis=1), references=p.label_ids)
+
+ config = AutoConfig.from_pretrained(
+ model_args.config_name or model_args.model_name_or_path,
+ num_labels=len(labels),
+ label2id=label2id,
+ id2label=id2label,
+ finetuning_task="image-classification",
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ model = AutoModelForImageClassification.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ ignore_mismatched_sizes=model_args.ignore_mismatched_sizes,
+ )
+ image_processor = AutoImageProcessor.from_pretrained(
+ model_args.image_processor_name or model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ # Define torchvision transforms to be applied to each image.
+ if isinstance(image_processor, TimmWrapperImageProcessor):
+ _train_transforms = image_processor.train_transforms
+ _val_transforms = image_processor.val_transforms
+ else:
+ if "shortest_edge" in image_processor.size:
+ size = image_processor.size["shortest_edge"]
+ else:
+ size = (image_processor.size["height"], image_processor.size["width"])
+
+ # Create normalization transform
+ if hasattr(image_processor, "image_mean") and hasattr(image_processor, "image_std"):
+ normalize = Normalize(mean=image_processor.image_mean, std=image_processor.image_std)
+ else:
+ normalize = Lambda(lambda x: x)
+ _train_transforms = Compose(
+ [
+ RandomResizedCrop(size),
+ RandomHorizontalFlip(),
+ ToTensor(),
+ normalize,
+ ]
+ )
+ _val_transforms = Compose(
+ [
+ Resize(size),
+ CenterCrop(size),
+ ToTensor(),
+ normalize,
+ ]
+ )
+
+ def train_transforms(example_batch):
+ """Apply _train_transforms across a batch."""
+ example_batch["pixel_values"] = [
+ _train_transforms(pil_img.convert("RGB")) for pil_img in example_batch[data_args.image_column_name]
+ ]
+ return example_batch
+
+ def val_transforms(example_batch):
+ """Apply _val_transforms across a batch."""
+ example_batch["pixel_values"] = [
+ _val_transforms(pil_img.convert("RGB")) for pil_img in example_batch[data_args.image_column_name]
+ ]
+ return example_batch
+
+ if training_args.do_train:
+ if "train" not in dataset:
+ raise ValueError("--do_train requires a train dataset")
+ if data_args.max_train_samples is not None:
+ dataset["train"] = (
+ dataset["train"].shuffle(seed=training_args.seed).select(range(data_args.max_train_samples))
+ )
+ # Set the training transforms
+ dataset["train"].set_transform(train_transforms)
+
+ if training_args.do_eval:
+ if "validation" not in dataset:
+ raise ValueError("--do_eval requires a validation dataset")
+ if data_args.max_eval_samples is not None:
+ dataset["validation"] = (
+ dataset["validation"].shuffle(seed=training_args.seed).select(range(data_args.max_eval_samples))
+ )
+ # Set the validation transforms
+ dataset["validation"].set_transform(val_transforms)
+
+ # Initialize our trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=dataset["train"] if training_args.do_train else None,
+ eval_dataset=dataset["validation"] if training_args.do_eval else None,
+ compute_metrics=compute_metrics,
+ processing_class=image_processor,
+ data_collator=collate_fn,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model()
+ trainer.log_metrics("train", train_result.metrics)
+ trainer.save_metrics("train", train_result.metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ metrics = trainer.evaluate()
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ # Write model card and (optionally) push to hub
+ kwargs = {
+ "finetuned_from": model_args.model_name_or_path,
+ "tasks": "image-classification",
+ "dataset": data_args.dataset_name,
+ "tags": ["image-classification", "vision"],
+ }
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-classification/run_image_classification_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-classification/run_image_classification_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..0dc3e11f08abc7b45aa7e503241d2903773294c6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-classification/run_image_classification_no_trainer.py
@@ -0,0 +1,646 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Finetuning any 🤗 Transformers model for image classification leveraging 🤗 Accelerate."""
+
+import argparse
+import json
+import logging
+import math
+import os
+from pathlib import Path
+
+import datasets
+import evaluate
+import torch
+from accelerate import Accelerator
+from accelerate.logging import get_logger
+from accelerate.utils import set_seed
+from datasets import load_dataset
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from torchvision.transforms import (
+ CenterCrop,
+ Compose,
+ Lambda,
+ Normalize,
+ RandomHorizontalFlip,
+ RandomResizedCrop,
+ Resize,
+ ToTensor,
+)
+from tqdm.auto import tqdm
+
+import transformers
+from transformers import AutoConfig, AutoImageProcessor, AutoModelForImageClassification, SchedulerType, get_scheduler
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+logger = get_logger(__name__)
+
+require_version("datasets>=2.0.0", "To fix: pip install -r examples/pytorch/image-classification/requirements.txt")
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Fine-tune a Transformers model on an image classification dataset")
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ default="cifar10",
+ help=(
+ "The name of the Dataset (from the HuggingFace hub) to train on (could be your own, possibly private,"
+ " dataset)."
+ ),
+ )
+ parser.add_argument("--train_dir", type=str, default=None, help="A folder containing the training data.")
+ parser.add_argument("--validation_dir", type=str, default=None, help="A folder containing the validation data.")
+ parser.add_argument(
+ "--max_train_samples",
+ type=int,
+ default=None,
+ help=(
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ ),
+ )
+ parser.add_argument(
+ "--max_eval_samples",
+ type=int,
+ default=None,
+ help=(
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ ),
+ )
+ parser.add_argument(
+ "--train_val_split",
+ type=float,
+ default=0.15,
+ help="Percent to split off of train for validation",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ default="google/vit-base-patch16-224-in21k",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--trust_remote_code",
+ action="store_true",
+ help=(
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ parser.add_argument(
+ "--ignore_mismatched_sizes",
+ action="store_true",
+ help="Whether or not to enable to load a pretrained model whose head dimensions are different.",
+ )
+ parser.add_argument(
+ "--image_column_name",
+ type=str,
+ default="image",
+ help="The name of the dataset column containing the image data. Defaults to 'image'.",
+ )
+ parser.add_argument(
+ "--label_column_name",
+ type=str,
+ default="label",
+ help="The name of the dataset column containing the labels. Defaults to 'label'.",
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+ if args.dataset_name is None and args.train_dir is None and args.validation_dir is None:
+ raise ValueError("Need either a dataset name or a training/validation folder.")
+
+ if args.push_to_hub or args.with_tracking:
+ if args.output_dir is None:
+ raise ValueError(
+ "Need an `output_dir` to create a repo when `--push_to_hub` or `with_tracking` is specified."
+ )
+
+ if args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+
+ return args
+
+
+def main():
+ args = parse_args()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_image_classification_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+ accelerator_log_kwargs = {}
+
+ if args.with_tracking:
+ accelerator_log_kwargs["log_with"] = args.report_to
+ accelerator_log_kwargs["project_dir"] = args.output_dir
+
+ accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
+
+ logger.info(accelerator.state)
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Get the datasets: you can either provide your own training and evaluation files (see below)
+ # or specify a Dataset from the hub (the dataset will be downloaded automatically from the datasets Hub).
+
+ # In distributed training, the load_dataset function guarantees that only one local process can concurrently
+ # download the dataset.
+ if args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ dataset = load_dataset(args.dataset_name, trust_remote_code=args.trust_remote_code)
+ else:
+ data_files = {}
+ if args.train_dir is not None:
+ data_files["train"] = os.path.join(args.train_dir, "**")
+ if args.validation_dir is not None:
+ data_files["validation"] = os.path.join(args.validation_dir, "**")
+ dataset = load_dataset(
+ "imagefolder",
+ data_files=data_files,
+ )
+ # See more about loading custom images at
+ # https://huggingface.co/docs/datasets/v2.0.0/en/image_process#imagefolder.
+
+ dataset_column_names = dataset["train"].column_names if "train" in dataset else dataset["validation"].column_names
+ if args.image_column_name not in dataset_column_names:
+ raise ValueError(
+ f"--image_column_name {args.image_column_name} not found in dataset '{args.dataset_name}'. "
+ "Make sure to set `--image_column_name` to the correct audio column - one of "
+ f"{', '.join(dataset_column_names)}."
+ )
+ if args.label_column_name not in dataset_column_names:
+ raise ValueError(
+ f"--label_column_name {args.label_column_name} not found in dataset '{args.dataset_name}'. "
+ "Make sure to set `--label_column_name` to the correct text column - one of "
+ f"{', '.join(dataset_column_names)}."
+ )
+
+ # If we don't have a validation split, split off a percentage of train as validation.
+ args.train_val_split = None if "validation" in dataset.keys() else args.train_val_split
+ if isinstance(args.train_val_split, float) and args.train_val_split > 0.0:
+ split = dataset["train"].train_test_split(args.train_val_split)
+ dataset["train"] = split["train"]
+ dataset["validation"] = split["test"]
+
+ # Prepare label mappings.
+ # We'll include these in the model's config to get human readable labels in the Inference API.
+ labels = dataset["train"].features[args.label_column_name].names
+ label2id = {label: str(i) for i, label in enumerate(labels)}
+ id2label = {str(i): label for i, label in enumerate(labels)}
+
+ # Load pretrained model and image processor
+ #
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config = AutoConfig.from_pretrained(
+ args.model_name_or_path,
+ num_labels=len(labels),
+ id2label=id2label,
+ label2id=label2id,
+ finetuning_task="image-classification",
+ trust_remote_code=args.trust_remote_code,
+ )
+ image_processor = AutoImageProcessor.from_pretrained(
+ args.model_name_or_path,
+ trust_remote_code=args.trust_remote_code,
+ )
+ model = AutoModelForImageClassification.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ ignore_mismatched_sizes=args.ignore_mismatched_sizes,
+ trust_remote_code=args.trust_remote_code,
+ )
+
+ # Preprocessing the datasets
+
+ # Define torchvision transforms to be applied to each image.
+ if "shortest_edge" in image_processor.size:
+ size = image_processor.size["shortest_edge"]
+ else:
+ size = (image_processor.size["height"], image_processor.size["width"])
+ normalize = (
+ Normalize(mean=image_processor.image_mean, std=image_processor.image_std)
+ if hasattr(image_processor, "image_mean") and hasattr(image_processor, "image_std")
+ else Lambda(lambda x: x)
+ )
+ train_transforms = Compose(
+ [
+ RandomResizedCrop(size),
+ RandomHorizontalFlip(),
+ ToTensor(),
+ normalize,
+ ]
+ )
+ val_transforms = Compose(
+ [
+ Resize(size),
+ CenterCrop(size),
+ ToTensor(),
+ normalize,
+ ]
+ )
+
+ def preprocess_train(example_batch):
+ """Apply _train_transforms across a batch."""
+ example_batch["pixel_values"] = [
+ train_transforms(image.convert("RGB")) for image in example_batch[args.image_column_name]
+ ]
+ return example_batch
+
+ def preprocess_val(example_batch):
+ """Apply _val_transforms across a batch."""
+ example_batch["pixel_values"] = [
+ val_transforms(image.convert("RGB")) for image in example_batch[args.image_column_name]
+ ]
+ return example_batch
+
+ with accelerator.main_process_first():
+ if args.max_train_samples is not None:
+ dataset["train"] = dataset["train"].shuffle(seed=args.seed).select(range(args.max_train_samples))
+ # Set the training transforms
+ train_dataset = dataset["train"].with_transform(preprocess_train)
+ if args.max_eval_samples is not None:
+ dataset["validation"] = dataset["validation"].shuffle(seed=args.seed).select(range(args.max_eval_samples))
+ # Set the validation transforms
+ eval_dataset = dataset["validation"].with_transform(preprocess_val)
+
+ # DataLoaders creation:
+ def collate_fn(examples):
+ pixel_values = torch.stack([example["pixel_values"] for example in examples])
+ labels = torch.tensor([example[args.label_column_name] for example in examples])
+ return {"pixel_values": pixel_values, "labels": labels}
+
+ train_dataloader = DataLoader(
+ train_dataset, shuffle=True, collate_fn=collate_fn, batch_size=args.per_device_train_batch_size
+ )
+ eval_dataloader = DataLoader(eval_dataset, collate_fn=collate_fn, batch_size=args.per_device_eval_batch_size)
+
+ # Optimizer
+ # Split weights in two groups, one with weight decay and the other not.
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
+ num_training_steps=args.max_train_steps
+ if overrode_max_train_steps
+ else args.max_train_steps * accelerator.num_processes,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("image_classification_no_trainer", experiment_config)
+
+ # Get the metric function
+ metric = evaluate.load("accuracy")
+
+ # Train!
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ checkpoint_path = args.resume_from_checkpoint
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ checkpoint_path = path
+ path = os.path.basename(checkpoint_path)
+
+ accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
+ accelerator.load_state(checkpoint_path)
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ completed_steps = resume_step // args.gradient_accumulation_steps
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We skip the first `n` batches in the dataloader when resuming from a checkpoint
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ with accelerator.accumulate(model):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # Checks if the accelerator has performed an optimization step behind the scenes
+ if accelerator.sync_gradients:
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir,
+ is_main_process=accelerator.is_main_process,
+ save_function=accelerator.save,
+ )
+ if accelerator.is_main_process:
+ image_processor.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if completed_steps >= args.max_train_steps:
+ break
+
+ model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ logger.info(f"epoch {epoch}: {eval_metric}")
+
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "accuracy": eval_metric,
+ "train_loss": total_loss.item() / len(train_dataloader),
+ "epoch": epoch,
+ "step": completed_steps,
+ },
+ step=completed_steps,
+ )
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ image_processor.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if args.checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.with_tracking:
+ accelerator.end_training()
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ image_processor.save_pretrained(args.output_dir)
+ if args.push_to_hub:
+ api.upload_folder(
+ commit_message="End of training",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+ all_results = {f"eval_{k}": v for k, v in eval_metric.items()}
+ with open(os.path.join(args.output_dir, "all_results.json"), "w") as f:
+ json.dump(all_results, f)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-pretraining/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-pretraining/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..88c71e643e4c24ee06e59a816ce98b879fa69f1d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-pretraining/README.md
@@ -0,0 +1,256 @@
+
+
+# Image pretraining examples
+
+This directory contains Python scripts that allow you to pre-train Transformer-based vision models (like [ViT](https://huggingface.co/docs/transformers/model_doc/vit), [Swin Transformer](https://huggingface.co/docs/transformers/model_doc/swin)) on your own data, after which you can easily load the weights into a [`AutoModelForImageClassification`](https://huggingface.co/docs/transformers/model_doc/auto#transformers.AutoModelForImageClassification). It currently includes scripts for:
+- [SimMIM](#simmim) (by Microsoft Research)
+- [MAE](#mae) (by Facebook AI).
+
+NOTE: If you encounter problems/have suggestions for improvement, open an issue on Github and tag @NielsRogge.
+
+
+## SimMIM
+
+The `run_mim.py` script can be used to pre-train any Transformer-based vision model in the library (concretely, any model supported by the `AutoModelForMaskedImageModeling` API) for masked image modeling as proposed in [SimMIM: A Simple Framework for Masked Image Modeling](https://arxiv.org/abs/2111.09886) using PyTorch.
+
+ SimMIM framework. Taken from the original paper .
+
+The goal for the model is to predict raw pixel values for the masked patches, using just a linear layer as prediction head. The model is trained using a simple L1 loss.
+
+### Using datasets from 🤗 datasets
+
+Here we show how to pre-train a `ViT` from scratch for masked image modeling on the [cifar10](https://huggingface.co/datasets/cifar10) dataset.
+
+Alternatively, one can decide to further pre-train an already pre-trained (or fine-tuned) checkpoint from the [hub](https://huggingface.co/). This can be done by setting the `model_name_or_path` argument to "google/vit-base-patch16-224-in21k" for example (and not specifying the `model_type` argument).
+
+```bash
+!python run_mim.py \
+ --model_type vit \
+ --output_dir ./outputs/ \
+ --overwrite_output_dir \
+ --remove_unused_columns False \
+ --label_names bool_masked_pos \
+ --do_train \
+ --do_eval \
+ --learning_rate 2e-5 \
+ --weight_decay 0.05 \
+ --num_train_epochs 100 \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 8 \
+ --logging_strategy steps \
+ --logging_steps 10 \
+ --eval_strategy epoch \
+ --save_strategy epoch \
+ --load_best_model_at_end True \
+ --save_total_limit 3 \
+ --seed 1337
+```
+
+Here, we train for 100 epochs with a learning rate of 2e-5. Note that the SimMIM authors used a more sophisticated learning rate schedule, see the [config files](https://github.com/microsoft/SimMIM/blob/main/configs/vit_base__800ep/simmim_pretrain__vit_base__img224__800ep.yaml) for more info. One can easily tweak the script to include this learning rate schedule (several learning rate schedulers are supported via the [training arguments](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments)).
+
+We can also for instance replicate the pre-training of a Swin Transformer using the same architecture as used by the SimMIM authors. For this, we first create a custom configuration and save it locally:
+
+```python
+from transformers import SwinConfig
+
+IMAGE_SIZE = 192
+PATCH_SIZE = 4
+EMBED_DIM = 128
+DEPTHS = [2, 2, 18, 2]
+NUM_HEADS = [4, 8, 16, 32]
+WINDOW_SIZE = 6
+
+config = SwinConfig(
+ image_size=IMAGE_SIZE,
+ patch_size=PATCH_SIZE,
+ embed_dim=EMBED_DIM,
+ depths=DEPTHS,
+ num_heads=NUM_HEADS,
+ window_size=WINDOW_SIZE,
+)
+config.save_pretrained("path_to_config")
+```
+
+Next, we can run the script by providing the path to this custom configuration (replace `path_to_config` below with your path):
+
+```bash
+!python run_mim.py \
+ --config_name_or_path path_to_config \
+ --model_type swin \
+ --output_dir ./outputs/ \
+ --overwrite_output_dir \
+ --remove_unused_columns False \
+ --label_names bool_masked_pos \
+ --do_train \
+ --do_eval \
+ --learning_rate 2e-5 \
+ --num_train_epochs 5 \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 8 \
+ --logging_strategy steps \
+ --logging_steps 10 \
+ --eval_strategy epoch \
+ --save_strategy epoch \
+ --load_best_model_at_end True \
+ --save_total_limit 3 \
+ --seed 1337
+```
+
+This will train a Swin Transformer from scratch.
+
+### Using your own data
+
+To use your own dataset, the training script expects the following directory structure:
+
+```bash
+root/dog/xxx.png
+root/dog/xxy.png
+root/dog/[...]/xxz.png
+
+root/cat/123.png
+root/cat/nsdf3.png
+root/cat/[...]/asd932_.png
+```
+
+Note that you can put images in dummy subfolders, whose names will be ignored by default (as labels aren't required). You can also just place all images into a single dummy subfolder. Once you've prepared your dataset, you can run the script like this:
+
+```bash
+python run_mim.py \
+ --model_type vit \
+ --dataset_name nateraw/image-folder \
+ --train_dir \
+ --output_dir ./outputs/ \
+ --remove_unused_columns False \
+ --label_names bool_masked_pos \
+ --do_train \
+ --do_eval
+```
+
+## MAE
+
+The `run_mae.py` script can be used to pre-train a Vision Transformer as a masked autoencoder (MAE), as proposed in [Masked Autoencoders Are Scalable Vision Learners](https://arxiv.org/abs/2111.06377). The script can be used to train a `ViTMAEForPreTraining` model in the Transformers library, using PyTorch. After self-supervised pre-training, one can load the weights of the encoder directly into a `ViTForImageClassification`. The MAE method allows for learning high-capacity models that generalize well: e.g., a vanilla ViT-Huge model achieves the best accuracy (87.8%) among methods that use only ImageNet-1K data.
+
+The goal for the model is to predict raw pixel values for the masked patches. As the model internally masks patches and learns to reconstruct them, there's no need for any labels. The model uses the mean squared error (MSE) between the reconstructed and original images in the pixel space.
+
+### Using datasets from 🤗 `datasets`
+
+One can use the following command to pre-train a `ViTMAEForPreTraining` model from scratch on the [cifar10](https://huggingface.co/datasets/cifar10) dataset:
+
+```bash
+python run_mae.py \
+ --dataset_name cifar10 \
+ --output_dir ./vit-mae-demo \
+ --remove_unused_columns False \
+ --label_names pixel_values \
+ --mask_ratio 0.75 \
+ --norm_pix_loss \
+ --do_train \
+ --do_eval \
+ --base_learning_rate 1.5e-4 \
+ --lr_scheduler_type cosine \
+ --weight_decay 0.05 \
+ --num_train_epochs 800 \
+ --warmup_ratio 0.05 \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 8 \
+ --logging_strategy steps \
+ --logging_steps 10 \
+ --eval_strategy epoch \
+ --save_strategy epoch \
+ --load_best_model_at_end True \
+ --save_total_limit 3 \
+ --seed 1337
+```
+
+Here we set:
+- `mask_ratio` to 0.75 (to mask 75% of the patches for each image)
+- `norm_pix_loss` to use normalized pixel values as target (the authors reported better representations with this enabled)
+- `base_learning_rate` to 1.5e-4. Note that the effective learning rate is computed by the [linear schedule](https://arxiv.org/abs/1706.02677): `lr` = `blr` * total training batch size / 256. The total training batch size is computed as `training_args.train_batch_size` * `training_args.gradient_accumulation_steps` * `training_args.world_size`.
+
+This replicates the same hyperparameters as used in the original implementation, as shown in the table below.
+
+ Original hyperparameters. Taken from the original paper .
+
+Alternatively, one can decide to further pre-train an already pre-trained (or fine-tuned) checkpoint from the [hub](https://huggingface.co/). This can be done by setting the `model_name_or_path` argument to "facebook/vit-mae-base" for example.
+
+
+### Using your own data
+
+To use your own dataset, the training script expects the following directory structure:
+
+```bash
+root/dog/xxx.png
+root/dog/xxy.png
+root/dog/[...]/xxz.png
+
+root/cat/123.png
+root/cat/nsdf3.png
+root/cat/[...]/asd932_.png
+```
+
+Note that you can put images in dummy subfolders, whose names will be ignored by default (as labels aren't required). You can also just place all images into a single dummy subfolder. Once you've prepared your dataset, you can run the script like this:
+
+```bash
+python run_mae.py \
+ --model_type vit_mae \
+ --dataset_name nateraw/image-folder \
+ --train_dir \
+ --output_dir ./outputs/ \
+ --remove_unused_columns False \
+ --label_names pixel_values \
+ --do_train \
+ --do_eval
+```
+
+#### 💡 The above will split the train dir into training and evaluation sets
+ - To control the split amount, use the `--train_val_split` flag.
+ - To provide your own validation split in its own directory, you can pass the `--validation_dir ` flag.
+
+
+## Sharing your model on 🤗 Hub
+
+0. If you haven't already, [sign up](https://huggingface.co/join) for a 🤗 account
+
+1. Make sure you have `git-lfs` installed and git set up.
+
+```bash
+$ apt install git-lfs
+$ git config --global user.email "you@example.com"
+$ git config --global user.name "Your Name"
+```
+
+2. Log in with your HuggingFace account credentials using `huggingface-cli`
+
+```bash
+$ huggingface-cli login
+# ...follow the prompts
+```
+
+3. When running the script, pass the following arguments:
+
+```bash
+python run_xxx.py \
+ --push_to_hub \
+ --push_to_hub_model_id \
+ ...
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-pretraining/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-pretraining/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..a789fee85eef5d028375e406c5ea7df85a56c738
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-pretraining/requirements.txt
@@ -0,0 +1,3 @@
+torch>=1.5.0
+torchvision>=0.6.0
+datasets>=1.8.0
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-pretraining/run_mae.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-pretraining/run_mae.py
new file mode 100644
index 0000000000000000000000000000000000000000..6308e250f5c341a3c27c9d835d8d24f219d38cda
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-pretraining/run_mae.py
@@ -0,0 +1,408 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from typing import Optional
+
+import torch
+from datasets import load_dataset
+from torchvision.transforms import Compose, Lambda, Normalize, RandomHorizontalFlip, RandomResizedCrop, ToTensor
+from torchvision.transforms.functional import InterpolationMode
+
+import transformers
+from transformers import (
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ ViTImageProcessor,
+ ViTMAEConfig,
+ ViTMAEForPreTraining,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+""" Pre-training a 🤗 ViT model as an MAE (masked autoencoder), as proposed in https://arxiv.org/abs/2111.06377."""
+
+logger = logging.getLogger(__name__)
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/image-pretraining/requirements.txt")
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ Using `HfArgumentParser` we can turn this class
+ into argparse arguments to be able to specify them on
+ the command line.
+ """
+
+ dataset_name: Optional[str] = field(
+ default="cifar10", metadata={"help": "Name of a dataset from the datasets package"}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ image_column_name: Optional[str] = field(
+ default=None, metadata={"help": "The column name of the images in the files."}
+ )
+ train_dir: Optional[str] = field(default=None, metadata={"help": "A folder containing the training data."})
+ validation_dir: Optional[str] = field(default=None, metadata={"help": "A folder containing the validation data."})
+ train_val_split: Optional[float] = field(
+ default=0.15, metadata={"help": "Percent to split off of train for validation."}
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+
+ def __post_init__(self):
+ data_files = {}
+ if self.train_dir is not None:
+ data_files["train"] = self.train_dir
+ if self.validation_dir is not None:
+ data_files["val"] = self.validation_dir
+ self.data_files = data_files if data_files else None
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/image processor we are going to pre-train.
+ """
+
+ model_name_or_path: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
+ )
+ },
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name_or_path"}
+ )
+ config_overrides: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Override some existing default config settings when a model is trained from scratch. Example: "
+ "n_embd=10,resid_pdrop=0.2,scale_attn_weights=false,summary_type=cls_index"
+ )
+ },
+ )
+ cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ image_processor_name: str = field(default=None, metadata={"help": "Name or path of preprocessor config."})
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ mask_ratio: float = field(
+ default=0.75, metadata={"help": "The ratio of the number of masked tokens in the input sequence."}
+ )
+ norm_pix_loss: bool = field(
+ default=True, metadata={"help": "Whether or not to train with normalized pixel values as target."}
+ )
+
+
+@dataclass
+class CustomTrainingArguments(TrainingArguments):
+ base_learning_rate: float = field(
+ default=1e-3, metadata={"help": "Base learning rate: absolute_lr = base_lr * total_batch_size / 256."}
+ )
+
+
+def collate_fn(examples):
+ pixel_values = torch.stack([example["pixel_values"] for example in examples])
+ return {"pixel_values": pixel_values}
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, CustomTrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_mae", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Initialize our dataset.
+ ds = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ data_files=data_args.data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+
+ # If we don't have a validation split, split off a percentage of train as validation.
+ data_args.train_val_split = None if "validation" in ds.keys() else data_args.train_val_split
+ if isinstance(data_args.train_val_split, float) and data_args.train_val_split > 0.0:
+ split = ds["train"].train_test_split(data_args.train_val_split)
+ ds["train"] = split["train"]
+ ds["validation"] = split["test"]
+
+ # Load pretrained model and image processor
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config_kwargs = {
+ "cache_dir": model_args.cache_dir,
+ "revision": model_args.model_revision,
+ "token": model_args.token,
+ }
+ if model_args.config_name:
+ config = ViTMAEConfig.from_pretrained(model_args.config_name, **config_kwargs)
+ elif model_args.model_name_or_path:
+ config = ViTMAEConfig.from_pretrained(model_args.model_name_or_path, **config_kwargs)
+ else:
+ config = ViTMAEConfig()
+ logger.warning("You are instantiating a new config instance from scratch.")
+ if model_args.config_overrides is not None:
+ logger.info(f"Overriding config: {model_args.config_overrides}")
+ config.update_from_string(model_args.config_overrides)
+ logger.info(f"New config: {config}")
+
+ # adapt config
+ config.update(
+ {
+ "mask_ratio": model_args.mask_ratio,
+ "norm_pix_loss": model_args.norm_pix_loss,
+ }
+ )
+
+ # create image processor
+ if model_args.image_processor_name:
+ image_processor = ViTImageProcessor.from_pretrained(model_args.image_processor_name, **config_kwargs)
+ elif model_args.model_name_or_path:
+ image_processor = ViTImageProcessor.from_pretrained(model_args.model_name_or_path, **config_kwargs)
+ else:
+ image_processor = ViTImageProcessor()
+
+ # create model
+ if model_args.model_name_or_path:
+ model = ViTMAEForPreTraining.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = ViTMAEForPreTraining(config)
+
+ if training_args.do_train:
+ column_names = ds["train"].column_names
+ else:
+ column_names = ds["validation"].column_names
+
+ if data_args.image_column_name is not None:
+ image_column_name = data_args.image_column_name
+ elif "image" in column_names:
+ image_column_name = "image"
+ elif "img" in column_names:
+ image_column_name = "img"
+ else:
+ image_column_name = column_names[0]
+
+ # transformations as done in original MAE paper
+ # source: https://github.com/facebookresearch/mae/blob/main/main_pretrain.py
+ if "shortest_edge" in image_processor.size:
+ size = image_processor.size["shortest_edge"]
+ else:
+ size = (image_processor.size["height"], image_processor.size["width"])
+ transforms = Compose(
+ [
+ Lambda(lambda img: img.convert("RGB") if img.mode != "RGB" else img),
+ RandomResizedCrop(size, scale=(0.2, 1.0), interpolation=InterpolationMode.BICUBIC),
+ RandomHorizontalFlip(),
+ ToTensor(),
+ Normalize(mean=image_processor.image_mean, std=image_processor.image_std),
+ ]
+ )
+
+ def preprocess_images(examples):
+ """Preprocess a batch of images by applying transforms."""
+
+ examples["pixel_values"] = [transforms(image) for image in examples[image_column_name]]
+ return examples
+
+ if training_args.do_train:
+ if "train" not in ds:
+ raise ValueError("--do_train requires a train dataset")
+ if data_args.max_train_samples is not None:
+ ds["train"] = ds["train"].shuffle(seed=training_args.seed).select(range(data_args.max_train_samples))
+ # Set the training transforms
+ ds["train"].set_transform(preprocess_images)
+
+ if training_args.do_eval:
+ if "validation" not in ds:
+ raise ValueError("--do_eval requires a validation dataset")
+ if data_args.max_eval_samples is not None:
+ ds["validation"] = (
+ ds["validation"].shuffle(seed=training_args.seed).select(range(data_args.max_eval_samples))
+ )
+ # Set the validation transforms
+ ds["validation"].set_transform(preprocess_images)
+
+ # Compute absolute learning rate
+ total_train_batch_size = (
+ training_args.train_batch_size * training_args.gradient_accumulation_steps * training_args.world_size
+ )
+ if training_args.base_learning_rate is not None:
+ training_args.learning_rate = training_args.base_learning_rate * total_train_batch_size / 256
+
+ # Initialize our trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=ds["train"] if training_args.do_train else None,
+ eval_dataset=ds["validation"] if training_args.do_eval else None,
+ processing_class=image_processor,
+ data_collator=collate_fn,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model()
+ trainer.log_metrics("train", train_result.metrics)
+ trainer.save_metrics("train", train_result.metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ metrics = trainer.evaluate()
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ # Write model card and (optionally) push to hub
+ kwargs = {
+ "tasks": "masked-auto-encoding",
+ "dataset": data_args.dataset_name,
+ "tags": ["masked-auto-encoding"],
+ }
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-pretraining/run_mim.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-pretraining/run_mim.py
new file mode 100644
index 0000000000000000000000000000000000000000..3721dc267c2273500792699c26ea41e6ba4bff84
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-pretraining/run_mim.py
@@ -0,0 +1,483 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from typing import Optional
+
+import numpy as np
+import torch
+from datasets import load_dataset
+from torchvision.transforms import Compose, Lambda, Normalize, RandomHorizontalFlip, RandomResizedCrop, ToTensor
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ IMAGE_PROCESSOR_MAPPING,
+ MODEL_FOR_MASKED_IMAGE_MODELING_MAPPING,
+ AutoConfig,
+ AutoImageProcessor,
+ AutoModelForMaskedImageModeling,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+""" Pre-training a 🤗 Transformers model for simple masked image modeling (SimMIM).
+Any model supported by the AutoModelForMaskedImageModeling API can be used.
+"""
+
+logger = logging.getLogger(__name__)
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/image-pretraining/requirements.txt")
+
+MODEL_CONFIG_CLASSES = list(MODEL_FOR_MASKED_IMAGE_MODELING_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ Using `HfArgumentParser` we can turn this class into argparse arguments to be able to
+ specify them on the command line.
+ """
+
+ dataset_name: Optional[str] = field(
+ default="cifar10", metadata={"help": "Name of a dataset from the datasets package"}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ image_column_name: Optional[str] = field(
+ default=None,
+ metadata={"help": "The column name of the images in the files. If not set, will try to use 'image' or 'img'."},
+ )
+ train_dir: Optional[str] = field(default=None, metadata={"help": "A folder containing the training data."})
+ validation_dir: Optional[str] = field(default=None, metadata={"help": "A folder containing the validation data."})
+ train_val_split: Optional[float] = field(
+ default=0.15, metadata={"help": "Percent to split off of train for validation."}
+ )
+ mask_patch_size: int = field(default=32, metadata={"help": "The size of the square patches to use for masking."})
+ mask_ratio: float = field(
+ default=0.6,
+ metadata={"help": "Percentage of patches to mask."},
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+
+ def __post_init__(self):
+ data_files = {}
+ if self.train_dir is not None:
+ data_files["train"] = self.train_dir
+ if self.validation_dir is not None:
+ data_files["val"] = self.validation_dir
+ self.data_files = data_files if data_files else None
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/image processor we are going to pre-train.
+ """
+
+ model_name_or_path: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The model checkpoint for weights initialization. Can be a local path to a pytorch_model.bin or a "
+ "checkpoint identifier on the hub. "
+ "Don't set if you want to train a model from scratch."
+ )
+ },
+ )
+ model_type: Optional[str] = field(
+ default=None,
+ metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
+ )
+ config_name_or_path: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ config_overrides: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Override some existing default config settings when a model is trained from scratch. Example: "
+ "n_embd=10,resid_pdrop=0.2,scale_attn_weights=false,summary_type=cls_index"
+ )
+ },
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store (cache) the pretrained models/datasets downloaded from the hub"},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ image_processor_name: str = field(default=None, metadata={"help": "Name or path of preprocessor config."})
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ image_size: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The size (resolution) of each image. If not specified, will use `image_size` of the configuration."
+ )
+ },
+ )
+ patch_size: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The size (resolution) of each patch. If not specified, will use `patch_size` of the configuration."
+ )
+ },
+ )
+ encoder_stride: Optional[int] = field(
+ default=None,
+ metadata={"help": "Stride to use for the encoder."},
+ )
+
+
+class MaskGenerator:
+ """
+ A class to generate boolean masks for the pretraining task.
+
+ A mask is a 1D tensor of shape (model_patch_size**2,) where the value is either 0 or 1,
+ where 1 indicates "masked".
+ """
+
+ def __init__(self, input_size=192, mask_patch_size=32, model_patch_size=4, mask_ratio=0.6):
+ self.input_size = input_size
+ self.mask_patch_size = mask_patch_size
+ self.model_patch_size = model_patch_size
+ self.mask_ratio = mask_ratio
+
+ if self.input_size % self.mask_patch_size != 0:
+ raise ValueError("Input size must be divisible by mask patch size")
+ if self.mask_patch_size % self.model_patch_size != 0:
+ raise ValueError("Mask patch size must be divisible by model patch size")
+
+ self.rand_size = self.input_size // self.mask_patch_size
+ self.scale = self.mask_patch_size // self.model_patch_size
+
+ self.token_count = self.rand_size**2
+ self.mask_count = int(np.ceil(self.token_count * self.mask_ratio))
+
+ def __call__(self):
+ mask_idx = np.random.permutation(self.token_count)[: self.mask_count]
+ mask = np.zeros(self.token_count, dtype=int)
+ mask[mask_idx] = 1
+
+ mask = mask.reshape((self.rand_size, self.rand_size))
+ mask = mask.repeat(self.scale, axis=0).repeat(self.scale, axis=1)
+
+ return torch.tensor(mask.flatten())
+
+
+def collate_fn(examples):
+ pixel_values = torch.stack([example["pixel_values"] for example in examples])
+ mask = torch.stack([example["mask"] for example in examples])
+ return {"pixel_values": pixel_values, "bool_masked_pos": mask}
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_mim", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Initialize our dataset.
+ ds = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ data_files=data_args.data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ # If we don't have a validation split, split off a percentage of train as validation.
+ data_args.train_val_split = None if "validation" in ds.keys() else data_args.train_val_split
+ if isinstance(data_args.train_val_split, float) and data_args.train_val_split > 0.0:
+ split = ds["train"].train_test_split(data_args.train_val_split)
+ ds["train"] = split["train"]
+ ds["validation"] = split["test"]
+
+ # Create config
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config_kwargs = {
+ "cache_dir": model_args.cache_dir,
+ "revision": model_args.model_revision,
+ "token": model_args.token,
+ "trust_remote_code": model_args.trust_remote_code,
+ }
+ if model_args.config_name_or_path:
+ config = AutoConfig.from_pretrained(model_args.config_name_or_path, **config_kwargs)
+ elif model_args.model_name_or_path:
+ config = AutoConfig.from_pretrained(model_args.model_name_or_path, **config_kwargs)
+ else:
+ config = CONFIG_MAPPING[model_args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+ if model_args.config_overrides is not None:
+ logger.info(f"Overriding config: {model_args.config_overrides}")
+ config.update_from_string(model_args.config_overrides)
+ logger.info(f"New config: {config}")
+
+ # make sure the decoder_type is "simmim" (only relevant for BEiT)
+ if hasattr(config, "decoder_type"):
+ config.decoder_type = "simmim"
+
+ # adapt config
+ model_args.image_size = model_args.image_size if model_args.image_size is not None else config.image_size
+ model_args.patch_size = model_args.patch_size if model_args.patch_size is not None else config.patch_size
+ model_args.encoder_stride = (
+ model_args.encoder_stride if model_args.encoder_stride is not None else config.encoder_stride
+ )
+
+ config.update(
+ {
+ "image_size": model_args.image_size,
+ "patch_size": model_args.patch_size,
+ "encoder_stride": model_args.encoder_stride,
+ }
+ )
+
+ # create image processor
+ if model_args.image_processor_name:
+ image_processor = AutoImageProcessor.from_pretrained(model_args.image_processor_name, **config_kwargs)
+ elif model_args.model_name_or_path:
+ image_processor = AutoImageProcessor.from_pretrained(model_args.model_name_or_path, **config_kwargs)
+ else:
+ IMAGE_PROCESSOR_TYPES = {
+ conf.model_type: image_processor_class for conf, image_processor_class in IMAGE_PROCESSOR_MAPPING.items()
+ }
+ image_processor = IMAGE_PROCESSOR_TYPES[model_args.model_type]()
+
+ # create model
+ if model_args.model_name_or_path:
+ model = AutoModelForMaskedImageModeling.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = AutoModelForMaskedImageModeling.from_config(config, trust_remote_code=model_args.trust_remote_code)
+
+ if training_args.do_train:
+ column_names = ds["train"].column_names
+ else:
+ column_names = ds["validation"].column_names
+
+ if data_args.image_column_name is not None:
+ image_column_name = data_args.image_column_name
+ elif "image" in column_names:
+ image_column_name = "image"
+ elif "img" in column_names:
+ image_column_name = "img"
+ else:
+ image_column_name = column_names[0]
+
+ # transformations as done in original SimMIM paper
+ # source: https://github.com/microsoft/SimMIM/blob/main/data/data_simmim.py
+ transforms = Compose(
+ [
+ Lambda(lambda img: img.convert("RGB") if img.mode != "RGB" else img),
+ RandomResizedCrop(model_args.image_size, scale=(0.67, 1.0), ratio=(3.0 / 4.0, 4.0 / 3.0)),
+ RandomHorizontalFlip(),
+ ToTensor(),
+ Normalize(mean=image_processor.image_mean, std=image_processor.image_std),
+ ]
+ )
+
+ # create mask generator
+ mask_generator = MaskGenerator(
+ input_size=model_args.image_size,
+ mask_patch_size=data_args.mask_patch_size,
+ model_patch_size=model_args.patch_size,
+ mask_ratio=data_args.mask_ratio,
+ )
+
+ def preprocess_images(examples):
+ """Preprocess a batch of images by applying transforms + creating a corresponding mask, indicating
+ which patches to mask."""
+
+ examples["pixel_values"] = [transforms(image) for image in examples[image_column_name]]
+ examples["mask"] = [mask_generator() for i in range(len(examples[image_column_name]))]
+
+ return examples
+
+ if training_args.do_train:
+ if "train" not in ds:
+ raise ValueError("--do_train requires a train dataset")
+ if data_args.max_train_samples is not None:
+ ds["train"] = ds["train"].shuffle(seed=training_args.seed).select(range(data_args.max_train_samples))
+ # Set the training transforms
+ ds["train"].set_transform(preprocess_images)
+
+ if training_args.do_eval:
+ if "validation" not in ds:
+ raise ValueError("--do_eval requires a validation dataset")
+ if data_args.max_eval_samples is not None:
+ ds["validation"] = (
+ ds["validation"].shuffle(seed=training_args.seed).select(range(data_args.max_eval_samples))
+ )
+ # Set the validation transforms
+ ds["validation"].set_transform(preprocess_images)
+
+ # Initialize our trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=ds["train"] if training_args.do_train else None,
+ eval_dataset=ds["validation"] if training_args.do_eval else None,
+ processing_class=image_processor,
+ data_collator=collate_fn,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model()
+ trainer.log_metrics("train", train_result.metrics)
+ trainer.save_metrics("train", train_result.metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ metrics = trainer.evaluate()
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ # Write model card and (optionally) push to hub
+ kwargs = {
+ "finetuned_from": model_args.model_name_or_path,
+ "tasks": "masked-image-modeling",
+ "dataset": data_args.dataset_name,
+ "tags": ["masked-image-modeling"],
+ }
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-pretraining/run_mim_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-pretraining/run_mim_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..0d8496bb3fed15cbc1168f15b7304245a0476be2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/image-pretraining/run_mim_no_trainer.py
@@ -0,0 +1,804 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2023 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+
+import argparse
+import logging
+import math
+import os
+from pathlib import Path
+
+import datasets
+import numpy as np
+import torch
+from accelerate import Accelerator, DistributedType
+from accelerate.utils import set_seed
+from datasets import load_dataset
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from torchvision.transforms import Compose, Lambda, Normalize, RandomHorizontalFlip, RandomResizedCrop, ToTensor
+from tqdm.auto import tqdm
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ IMAGE_PROCESSOR_MAPPING,
+ MODEL_FOR_MASKED_IMAGE_MODELING_MAPPING,
+ AutoConfig,
+ AutoImageProcessor,
+ AutoModelForMaskedImageModeling,
+ SchedulerType,
+ get_scheduler,
+)
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+""" Pre-training a 🤗 Transformers model for simple masked image modeling (SimMIM)
+without using HuggingFace Trainer.
+Any model supported by the AutoModelForMaskedImageModeling API can be used.
+"""
+
+logger = logging.getLogger(__name__)
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/image-pretraining/requirements.txt")
+
+MODEL_CONFIG_CLASSES = list(MODEL_FOR_MASKED_IMAGE_MODELING_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(
+ description="Finetune a transformers model on a simple Masked Image Modeling task"
+ )
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ default="cifar10",
+ help="Name of a dataset from the datasets package",
+ )
+ parser.add_argument(
+ "--dataset_config_name",
+ type=str,
+ default=None,
+ help="The configuration name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--image_column_name",
+ type=str,
+ default=None,
+ help="The column name of the images in the files. If not set, will try to use 'image' or 'img'.",
+ )
+ parser.add_argument(
+ "--train_dir",
+ type=str,
+ default=None,
+ help="A folder containing the training data.",
+ )
+ parser.add_argument(
+ "--validation_dir",
+ type=None,
+ default=None,
+ help="A folder containing the validation data.",
+ )
+ parser.add_argument(
+ "--train_val_split",
+ type=float,
+ default=0.15,
+ help="Percent to split off of train for validation.",
+ )
+ parser.add_argument(
+ "--mask_patch_size",
+ type=int,
+ default=32,
+ help="The size of the square patches to use for masking.",
+ )
+ parser.add_argument(
+ "--mask_ratio",
+ type=float,
+ default=0.6,
+ help="Percentage of patches to mask.",
+ )
+ parser.add_argument(
+ "--max_train_samples",
+ type=int,
+ default=None,
+ help=(
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ ),
+ )
+ parser.add_argument(
+ "--max_eval_samples",
+ type=int,
+ default=None,
+ help=(
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ ),
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ default=None,
+ help=(
+ "The model checkpoint for weights initialization. Can be a local path to a pytorch_model.bin or a "
+ "checkpoint identifier on the hub. "
+ "Don't set if you want to train a model from scratch."
+ ),
+ )
+ parser.add_argument(
+ "--model_type",
+ type=str,
+ default=None,
+ help="If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES),
+ )
+ parser.add_argument(
+ "--config_name_or_path",
+ type=str,
+ default=None,
+ help="Pretrained config name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--config_overrides",
+ type=str,
+ default=None,
+ help=(
+ "Override some existing default config settings when a model is trained from scratch. Example: "
+ "n_embd=10,resid_pdrop=0.2,scale_attn_weights=false,summary_type=cls_index"
+ ),
+ )
+ parser.add_argument(
+ "--cache_dir",
+ type=str,
+ default=None,
+ help="Where do you want to store (cache) the pretrained models/datasets downloaded from the hub",
+ )
+ parser.add_argument(
+ "--model_revision",
+ type=str,
+ default="main",
+ help="The specific model version to use (can be a branch name, tag name or commit id).",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--image_processor_name",
+ type=str,
+ default=None,
+ help="Name or path of preprocessor config.",
+ )
+ parser.add_argument(
+ "--token",
+ type=str,
+ default=None,
+ help=(
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ ),
+ )
+ parser.add_argument(
+ "--trust_remote_code",
+ action="store_true",
+ help=(
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--image_size",
+ type=int,
+ default=None,
+ help="The size (resolution) of each image. If not specified, will use `image_size` of the configuration.",
+ )
+ parser.add_argument(
+ "--patch_size",
+ type=int,
+ default=None,
+ help="The size (resolution) of each patch. If not specified, will use `patch_size` of the configuration.",
+ )
+ parser.add_argument(
+ "--encoder_stride",
+ type=int,
+ default=None,
+ help={"help": "Stride to use for the encoder."},
+ )
+ parser.add_argument(
+ "--push_to_hub",
+ action="store_true",
+ help="Whether or not to push the model to the Hub.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ parser.add_argument(
+ "--seed",
+ type=int,
+ default=None,
+ help="A seed for reproducible training.",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="The initial learning rate for [`AdamW`] optimizer.",
+ )
+ parser.add_argument(
+ "--weight_decay",
+ type=float,
+ default=0.0,
+ help="Weight decay to use.",
+ )
+ parser.add_argument(
+ "--num_train_epochs",
+ type=float,
+ default=3.0,
+ help="Total number of training epochs to perform (if not an integer, will perform the decimal part percents of the last epoch before stopping training).",
+ )
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps",
+ type=int,
+ default=0,
+ help="Number of steps for the warmup in the lr scheduler.",
+ )
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--output_dir",
+ type=str,
+ default=None,
+ help="Where to store the final model.",
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+ data_files = {}
+ if args.train_dir is not None:
+ data_files["train"] = args.train_dir
+ if args.validation_dir is not None:
+ data_files["val"] = args.validation_dir
+ args.data_files = data_files if data_files else None
+
+ if args.push_to_hub:
+ assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
+
+ return args
+
+
+class MaskGenerator:
+ """
+ A class to generate boolean masks for the pretraining task.
+
+ A mask is a 1D tensor of shape (model_patch_size**2,) where the value is either 0 or 1,
+ where 1 indicates "masked".
+ """
+
+ def __init__(self, input_size=192, mask_patch_size=32, model_patch_size=4, mask_ratio=0.6):
+ self.input_size = input_size
+ self.mask_patch_size = mask_patch_size
+ self.model_patch_size = model_patch_size
+ self.mask_ratio = mask_ratio
+
+ if self.input_size % self.mask_patch_size != 0:
+ raise ValueError("Input size must be divisible by mask patch size")
+ if self.mask_patch_size % self.model_patch_size != 0:
+ raise ValueError("Mask patch size must be divisible by model patch size")
+
+ self.rand_size = self.input_size // self.mask_patch_size
+ self.scale = self.mask_patch_size // self.model_patch_size
+
+ self.token_count = self.rand_size**2
+ self.mask_count = int(np.ceil(self.token_count * self.mask_ratio))
+
+ def __call__(self):
+ mask_idx = np.random.permutation(self.token_count)[: self.mask_count]
+ mask = np.zeros(self.token_count, dtype=int)
+ mask[mask_idx] = 1
+
+ mask = mask.reshape((self.rand_size, self.rand_size))
+ mask = mask.repeat(self.scale, axis=0).repeat(self.scale, axis=1)
+
+ return torch.tensor(mask.flatten())
+
+
+def collate_fn(examples):
+ pixel_values = torch.stack([example["pixel_values"] for example in examples])
+ mask = torch.stack([example["mask"] for example in examples])
+ return {"pixel_values": pixel_values, "bool_masked_pos": mask}
+
+
+def main():
+ args = parse_args()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_mim_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+ accelerator_log_kwargs = {}
+
+ if args.with_tracking:
+ accelerator_log_kwargs["log_with"] = args.report_to
+ accelerator_log_kwargs["project_dir"] = args.output_dir
+
+ accelerator = Accelerator(
+ gradient_accumulation_steps=args.gradient_accumulation_steps,
+ **accelerator_log_kwargs,
+ )
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Initialize our dataset.
+ ds = load_dataset(
+ args.dataset_name,
+ args.dataset_config_name,
+ data_files=args.data_files,
+ cache_dir=args.cache_dir,
+ token=args.token,
+ trust_remote_code=args.trust_remote_code,
+ )
+
+ # If we don't have a validation split, split off a percentage of train as validation.
+ args.train_val_split = None if "validation" in ds.keys() else args.train_val_split
+ if isinstance(args.train_val_split, float) and args.train_val_split > 0.0:
+ split = ds["train"].train_test_split(args.train_val_split)
+ ds["train"] = split["train"]
+ ds["validation"] = split["test"]
+
+ # Create config
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config_kwargs = {
+ "cache_dir": args.cache_dir,
+ "revision": args.model_revision,
+ "token": args.token,
+ "trust_remote_code": args.trust_remote_code,
+ }
+ if args.config_name_or_path:
+ config = AutoConfig.from_pretrained(args.config_name_or_path, **config_kwargs)
+ elif args.model_name_or_path:
+ config = AutoConfig.from_pretrained(args.model_name_or_path, **config_kwargs)
+ else:
+ config = CONFIG_MAPPING[args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+ if args.config_overrides is not None:
+ logger.info(f"Overriding config: {args.config_overrides}")
+ config.update_from_string(args.config_overrides)
+ logger.info(f"New config: {config}")
+
+ # make sure the decoder_type is "simmim" (only relevant for BEiT)
+ if hasattr(config, "decoder_type"):
+ config.decoder_type = "simmim"
+
+ # adapt config
+ args.image_size = args.image_size if args.image_size is not None else config.image_size
+ args.patch_size = args.patch_size if args.patch_size is not None else config.patch_size
+ args.encoder_stride = args.encoder_stride if args.encoder_stride is not None else config.encoder_stride
+
+ config.update(
+ {
+ "image_size": args.image_size,
+ "patch_size": args.patch_size,
+ "encoder_stride": args.encoder_stride,
+ }
+ )
+
+ # create image processor
+ if args.image_processor_name:
+ image_processor = AutoImageProcessor.from_pretrained(args.image_processor_name, **config_kwargs)
+ elif args.model_name_or_path:
+ image_processor = AutoImageProcessor.from_pretrained(args.model_name_or_path, **config_kwargs)
+ else:
+ IMAGE_PROCESSOR_TYPES = {
+ conf.model_type: image_processor_class for conf, image_processor_class in IMAGE_PROCESSOR_MAPPING.items()
+ }
+ image_processor = IMAGE_PROCESSOR_TYPES[args.model_type]()
+
+ # create model
+ if args.model_name_or_path:
+ model = AutoModelForMaskedImageModeling.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ cache_dir=args.cache_dir,
+ revision=args.model_revision,
+ token=args.token,
+ trust_remote_code=args.trust_remote_code,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = AutoModelForMaskedImageModeling.from_config(
+ config,
+ token=args.token,
+ trust_remote_code=args.trust_remote_code,
+ )
+
+ column_names = ds["train"].column_names
+
+ if args.image_column_name is not None:
+ image_column_name = args.image_column_name
+ elif "image" in column_names:
+ image_column_name = "image"
+ elif "img" in column_names:
+ image_column_name = "img"
+ else:
+ image_column_name = column_names[0]
+
+ # transformations as done in original SimMIM paper
+ # source: https://github.com/microsoft/SimMIM/blob/main/data/data_simmim.py
+ transforms = Compose(
+ [
+ Lambda(lambda img: img.convert("RGB")),
+ RandomResizedCrop(args.image_size, scale=(0.67, 1.0), ratio=(3.0 / 4.0, 4.0 / 3.0)),
+ RandomHorizontalFlip(),
+ ToTensor(),
+ Normalize(mean=image_processor.image_mean, std=image_processor.image_std),
+ ]
+ )
+
+ # create mask generator
+ mask_generator = MaskGenerator(
+ input_size=args.image_size,
+ mask_patch_size=args.mask_patch_size,
+ model_patch_size=args.patch_size,
+ mask_ratio=args.mask_ratio,
+ )
+
+ def preprocess_images(examples):
+ """Preprocess a batch of images by applying transforms + creating a corresponding mask, indicating
+ which patches to mask."""
+
+ examples["pixel_values"] = [transforms(image) for image in examples[image_column_name]]
+ examples["mask"] = [mask_generator() for i in range(len(examples[image_column_name]))]
+
+ return examples
+
+ if args.max_train_samples is not None:
+ ds["train"] = ds["train"].shuffle(seed=args.seed).select(range(args.max_train_samples))
+ # Set the training transforms
+ ds["train"].set_transform(preprocess_images)
+
+ if args.max_eval_samples is not None:
+ ds["validation"] = ds["validation"].shuffle(seed=args.seed).select(range(args.max_eval_samples))
+ # Set the validation transforms
+ ds["validation"].set_transform(preprocess_images)
+
+ # DataLoaders creation:
+ train_dataloader = DataLoader(
+ ds["train"],
+ shuffle=True,
+ collate_fn=collate_fn,
+ batch_size=args.per_device_train_batch_size,
+ )
+ eval_dataloader = DataLoader(
+ ds["validation"],
+ collate_fn=collate_fn,
+ batch_size=args.per_device_eval_batch_size,
+ )
+
+ # Optimizer
+ # Split weights in two groups, one with weight decay and the other not.
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
+
+ # Note -> the training dataloader needs to be prepared before we grab his length below (cause its length will be
+ # shorter in multiprocess)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
+ num_training_steps=args.max_train_steps
+ if overrode_max_train_steps
+ else args.max_train_steps * accelerator.num_processes,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model,
+ optimizer,
+ train_dataloader,
+ eval_dataloader,
+ lr_scheduler,
+ )
+
+ # On TPU, the tie weights in our model have been disconnected, so we need to restore the ties.
+ if accelerator.distributed_type == DistributedType.TPU:
+ model.tie_weights()
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("mim_no_trainer", experiment_config)
+
+ # Train!
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(ds['train'])}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(int(args.max_train_steps)), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ checkpoint_path = args.resume_from_checkpoint
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ checkpoint_path = path
+ path = os.path.basename(checkpoint_path)
+
+ accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
+ accelerator.load_state(checkpoint_path)
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ completed_steps = resume_step // args.gradient_accumulation_steps
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We skip the first `n` batches in the dataloader when resuming from a checkpoint
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ with accelerator.accumulate(model):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # Checks if the accelerator has performed an optimization step behind the scenes
+ if accelerator.sync_gradients:
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if completed_steps >= args.max_train_steps:
+ break
+
+ model.eval()
+ losses = []
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+
+ loss = outputs.loss
+ losses.append(accelerator.gather_for_metrics(loss.repeat(args.per_device_eval_batch_size)))
+
+ losses = torch.cat(losses)
+ eval_loss = torch.mean(losses)
+
+ logger.info(f"epoch {epoch}: eval_loss: {eval_loss}")
+
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "eval_loss": eval_loss,
+ "train_loss": total_loss.item() / len(train_dataloader),
+ "epoch": epoch,
+ "step": completed_steps,
+ },
+ step=completed_steps,
+ )
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ image_processor.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if args.checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.with_tracking:
+ accelerator.end_training()
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ image_processor.save_pretrained(args.output_dir)
+ if args.push_to_hub:
+ api.upload_folder(
+ commit_message="End of training",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/instance-segmentation/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/instance-segmentation/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..339d7591523de763f81262b98c68eeff113a8815
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/instance-segmentation/README.md
@@ -0,0 +1,235 @@
+
+
+# Instance Segmentation Examples
+
+This directory contains two scripts that demonstrate how to fine-tune [MaskFormer](https://huggingface.co/docs/transformers/model_doc/maskformer) and [Mask2Former](https://huggingface.co/docs/transformers/model_doc/mask2former) for instance segmentation using PyTorch.
+For other instance segmentation models, such as [DETR](https://huggingface.co/docs/transformers/model_doc/detr) and [Conditional DETR](https://huggingface.co/docs/transformers/model_doc/conditional_detr), the scripts need to be adjusted to properly handle input and output data.
+
+Content:
+- [PyTorch Version with Trainer](#pytorch-version-with-trainer)
+- [PyTorch Version with Accelerate](#pytorch-version-with-accelerate)
+- [Reload and Perform Inference](#reload-and-perform-inference)
+- [Note on Custom Data](#note-on-custom-data)
+
+## PyTorch Version with Trainer
+
+This example is based on the script [`run_instance_segmentation.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/instance-segmentation/run_instance_segmentation.py).
+
+The script uses the [🤗 Trainer API](https://huggingface.co/docs/transformers/main_classes/trainer) to manage training automatically, including distributed environments.
+
+Here, we show how to fine-tune a [Mask2Former](https://huggingface.co/docs/transformers/model_doc/mask2former) model on a subsample of the [ADE20K](https://huggingface.co/datasets/zhoubolei/scene_parse_150) dataset. We created a [small dataset](https://huggingface.co/datasets/qubvel-hf/ade20k-mini) with approximately 2,000 images containing only "person" and "car" annotations; all other pixels are marked as "background."
+
+Here is the `label2id` mapping for this dataset:
+
+```python
+label2id = {
+ "background": 0,
+ "person": 1,
+ "car": 2,
+}
+```
+
+Since the `background` label is not an instance and we don't want to predict it, we will use `do_reduce_labels` to remove it from the data.
+
+Run the training with the following command:
+
+```bash
+python run_instance_segmentation.py \
+ --model_name_or_path facebook/mask2former-swin-tiny-coco-instance \
+ --output_dir finetune-instance-segmentation-ade20k-mini-mask2former \
+ --dataset_name qubvel-hf/ade20k-mini \
+ --do_reduce_labels \
+ --image_height 256 \
+ --image_width 256 \
+ --do_train \
+ --fp16 \
+ --num_train_epochs 40 \
+ --learning_rate 1e-5 \
+ --lr_scheduler_type constant \
+ --per_device_train_batch_size 8 \
+ --gradient_accumulation_steps 2 \
+ --dataloader_num_workers 8 \
+ --dataloader_persistent_workers \
+ --dataloader_prefetch_factor 4 \
+ --do_eval \
+ --evaluation_strategy epoch \
+ --logging_strategy epoch \
+ --save_strategy epoch \
+ --save_total_limit 2 \
+ --push_to_hub
+```
+
+The resulting model can be viewed [here](https://huggingface.co/qubvel-hf/finetune-instance-segmentation-ade20k-mini-mask2former). Always refer to the original paper for details on training hyperparameters. To improve model quality, consider:
+- Changing image size parameters (`--image_height`/`--image_width`)
+- Adjusting training parameters such as learning rate, batch size, warmup, optimizer, and more (see [TrainingArguments](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments))
+- Adding more image augmentations (we created a helpful [HF Space](https://huggingface.co/spaces/qubvel-hf/albumentations-demo) to choose some)
+
+You can also replace the model [checkpoint](https://huggingface.co/models?search=maskformer).
+
+## PyTorch Version with Accelerate
+
+This example is based on the script [`run_instance_segmentation_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/instance-segmentation/run_instance_segmentation_no_trainer.py).
+
+The script uses [🤗 Accelerate](https://github.com/huggingface/accelerate) to write your own training loop in PyTorch and run it on various environments, including CPU, multi-CPU, GPU, multi-GPU, and TPU, with support for mixed precision.
+
+First, configure the environment:
+
+```bash
+accelerate config
+```
+
+Answer the questions regarding your training environment. Then, run:
+
+```bash
+accelerate test
+```
+
+This command ensures everything is ready for training. Finally, launch training with:
+
+```bash
+accelerate launch run_instance_segmentation_no_trainer.py \
+ --model_name_or_path facebook/mask2former-swin-tiny-coco-instance \
+ --output_dir finetune-instance-segmentation-ade20k-mini-mask2former-no-trainer \
+ --dataset_name qubvel-hf/ade20k-mini \
+ --do_reduce_labels \
+ --image_height 256 \
+ --image_width 256 \
+ --num_train_epochs 40 \
+ --learning_rate 1e-5 \
+ --lr_scheduler_type constant \
+ --per_device_train_batch_size 8 \
+ --gradient_accumulation_steps 2 \
+ --dataloader_num_workers 8 \
+ --push_to_hub
+```
+
+With this setup, you can train on multiple GPUs, log everything to trackers (like Weights and Biases, Tensorboard), and regularly push your model to the hub (with the repo name set to `args.output_dir` under your HF username).
+With the default settings, the script fine-tunes a [Mask2Former](https://huggingface.co/docs/transformers/model_doc/mask2former) model on the sample of [ADE20K](https://huggingface.co/datasets/qubvel-hf/ade20k-mini) dataset. The resulting model can be viewed [here](https://huggingface.co/qubvel-hf/finetune-instance-segmentation-ade20k-mini-mask2former-no-trainer).
+
+## Reload and Perform Inference
+
+After training, you can easily load your trained model and perform inference as follows:
+
+```python
+import torch
+import requests
+import matplotlib.pyplot as plt
+
+from PIL import Image
+from transformers import Mask2FormerForUniversalSegmentation, Mask2FormerImageProcessor
+
+# Load image
+image = Image.open(requests.get("http://farm4.staticflickr.com/3017/3071497290_31f0393363_z.jpg", stream=True).raw)
+
+# Load model and image processor
+device = "cuda"
+checkpoint = "qubvel-hf/finetune-instance-segmentation-ade20k-mini-mask2former"
+
+model = Mask2FormerForUniversalSegmentation.from_pretrained(checkpoint, device_map=device)
+image_processor = Mask2FormerImageProcessor.from_pretrained(checkpoint)
+
+# Run inference on image
+inputs = image_processor(images=[image], return_tensors="pt").to(device)
+with torch.no_grad():
+ outputs = model(**inputs)
+
+# Post-process outputs
+outputs = image_processor.post_process_instance_segmentation(outputs, target_sizes=[(image.height, image.width)])
+
+print("Mask shape: ", outputs[0]["segmentation"].shape)
+print("Mask values: ", outputs[0]["segmentation"].unique())
+for segment in outputs[0]["segments_info"]:
+ print("Segment: ", segment)
+```
+
+```
+Mask shape: torch.Size([427, 640])
+Mask values: tensor([-1., 0., 1., 2., 3., 4., 5., 6.])
+Segment: {'id': 0, 'label_id': 0, 'was_fused': False, 'score': 0.946127}
+Segment: {'id': 1, 'label_id': 1, 'was_fused': False, 'score': 0.961582}
+Segment: {'id': 2, 'label_id': 1, 'was_fused': False, 'score': 0.968367}
+Segment: {'id': 3, 'label_id': 1, 'was_fused': False, 'score': 0.819527}
+Segment: {'id': 4, 'label_id': 1, 'was_fused': False, 'score': 0.655761}
+Segment: {'id': 5, 'label_id': 1, 'was_fused': False, 'score': 0.531299}
+Segment: {'id': 6, 'label_id': 1, 'was_fused': False, 'score': 0.929477}
+```
+
+Use the following code to visualize the results:
+
+```python
+import numpy as np
+import matplotlib.pyplot as plt
+
+segmentation = outputs[0]["segmentation"].numpy()
+
+plt.figure(figsize=(10, 10))
+plt.subplot(1, 2, 1)
+plt.imshow(np.array(image))
+plt.axis("off")
+plt.subplot(1, 2, 2)
+plt.imshow(segmentation)
+plt.axis("off")
+plt.show()
+```
+
+
+
+## Note on Custom Data
+
+Here is a short script demonstrating how to create your own dataset for instance segmentation and push it to the hub:
+
+> Note: Annotations should be represented as 3-channel images (similar to the [scene_parsing_150](https://huggingface.co/datasets/zhoubolei/scene_parse_150#instance_segmentation-1) dataset). The first channel is a semantic-segmentation map with values corresponding to `label2id`, the second is an instance-segmentation map where each instance has a unique value, and the third channel should be empty (filled with zeros).
+
+```python
+from datasets import Dataset, DatasetDict
+from datasets import Image as DatasetImage
+
+label2id = {
+ "background": 0,
+ "person": 1,
+ "car": 2,
+}
+
+train_split = {
+ "image": [, , , ...],
+ "annotation": [, , , ...],
+}
+
+validation_split = {
+ "image": [, , , ...],
+ "annotation": [, , , ...],
+}
+
+def create_instance_segmentation_dataset(label2id, **splits):
+ dataset_dict = {}
+ for split_name, split in splits.items():
+ split["semantic_class_to_id"] = [label2id] * len(split["image"])
+ dataset_split = (
+ Dataset.from_dict(split)
+ .cast_column("image", DatasetImage())
+ .cast_column("annotation", DatasetImage())
+ )
+ dataset_dict[split_name] = dataset_split
+ return DatasetDict(dataset_dict)
+
+dataset = create_instance_segmentation_dataset(label2id, train=train_split, validation=validation_split)
+dataset.push_to_hub("qubvel-hf/ade20k-nano")
+```
+
+Use this dataset for fine-tuning by specifying its name with `--dataset_name `.
+
+See also: [Dataset Creation Guide](https://huggingface.co/docs/datasets/image_dataset#create-an-image-dataset)
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/instance-segmentation/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/instance-segmentation/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..7772958dee7af88f31167f8fe2fb5af4fb1e1866
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/instance-segmentation/requirements.txt
@@ -0,0 +1,5 @@
+albumentations >= 1.4.16
+timm
+datasets
+torchmetrics
+pycocotools
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/instance-segmentation/run_instance_segmentation.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/instance-segmentation/run_instance_segmentation.py
new file mode 100644
index 0000000000000000000000000000000000000000..306e8085f6763f7c7ca49f7dfe89a94ee22ca13c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/instance-segmentation/run_instance_segmentation.py
@@ -0,0 +1,480 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+
+"""Finetuning 🤗 Transformers model for instance segmentation leveraging the Trainer API."""
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from functools import partial
+from typing import Any, Dict, List, Mapping, Optional
+
+import albumentations as A
+import numpy as np
+import torch
+from datasets import load_dataset
+from torchmetrics.detection.mean_ap import MeanAveragePrecision
+
+import transformers
+from transformers import (
+ AutoImageProcessor,
+ AutoModelForUniversalSegmentation,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+)
+from transformers.image_processing_utils import BatchFeature
+from transformers.trainer import EvalPrediction
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+logger = logging.getLogger(__name__)
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=2.0.0", "To fix: pip install -r examples/pytorch/instance-segmentation/requirements.txt")
+
+
+@dataclass
+class Arguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ Using `HfArgumentParser` we can turn this class into argparse arguments to be able to specify
+ them on the command line.
+ """
+
+ model_name_or_path: str = field(
+ default="facebook/mask2former-swin-tiny-coco-instance",
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"},
+ )
+ dataset_name: str = field(
+ default="qubvel-hf/ade20k-mini",
+ metadata={
+ "help": "Name of a dataset from the hub (could be your own, possibly private dataset hosted on the hub)."
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ image_height: Optional[int] = field(default=512, metadata={"help": "Image height after resizing."})
+ image_width: Optional[int] = field(default=512, metadata={"help": "Image width after resizing."})
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ do_reduce_labels: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "If background class is labeled as 0 and you want to remove it from the labels, set this flag to True."
+ )
+ },
+ )
+
+
+def augment_and_transform_batch(
+ examples: Mapping[str, Any], transform: A.Compose, image_processor: AutoImageProcessor
+) -> BatchFeature:
+ batch = {
+ "pixel_values": [],
+ "mask_labels": [],
+ "class_labels": [],
+ }
+
+ for pil_image, pil_annotation in zip(examples["image"], examples["annotation"]):
+ image = np.array(pil_image)
+ semantic_and_instance_masks = np.array(pil_annotation)[..., :2]
+
+ # Apply augmentations
+ output = transform(image=image, mask=semantic_and_instance_masks)
+
+ aug_image = output["image"]
+ aug_semantic_and_instance_masks = output["mask"]
+ aug_instance_mask = aug_semantic_and_instance_masks[..., 1]
+
+ # Create mapping from instance id to semantic id
+ unique_semantic_id_instance_id_pairs = np.unique(aug_semantic_and_instance_masks.reshape(-1, 2), axis=0)
+ instance_id_to_semantic_id = {
+ instance_id: semantic_id for semantic_id, instance_id in unique_semantic_id_instance_id_pairs
+ }
+
+ # Apply the image processor transformations: resizing, rescaling, normalization
+ model_inputs = image_processor(
+ images=[aug_image],
+ segmentation_maps=[aug_instance_mask],
+ instance_id_to_semantic_id=instance_id_to_semantic_id,
+ return_tensors="pt",
+ )
+
+ batch["pixel_values"].append(model_inputs.pixel_values[0])
+ batch["mask_labels"].append(model_inputs.mask_labels[0])
+ batch["class_labels"].append(model_inputs.class_labels[0])
+
+ return batch
+
+
+def collate_fn(examples):
+ batch = {}
+ batch["pixel_values"] = torch.stack([example["pixel_values"] for example in examples])
+ batch["class_labels"] = [example["class_labels"] for example in examples]
+ batch["mask_labels"] = [example["mask_labels"] for example in examples]
+ if "pixel_mask" in examples[0]:
+ batch["pixel_mask"] = torch.stack([example["pixel_mask"] for example in examples])
+ return batch
+
+
+@dataclass
+class ModelOutput:
+ class_queries_logits: torch.Tensor
+ masks_queries_logits: torch.Tensor
+
+
+def nested_cpu(tensors):
+ if isinstance(tensors, (list, tuple)):
+ return type(tensors)(nested_cpu(t) for t in tensors)
+ elif isinstance(tensors, Mapping):
+ return type(tensors)({k: nested_cpu(t) for k, t in tensors.items()})
+ elif isinstance(tensors, torch.Tensor):
+ return tensors.cpu().detach()
+ else:
+ return tensors
+
+
+class Evaluator:
+ """
+ Compute metrics for the instance segmentation task.
+ """
+
+ def __init__(
+ self,
+ image_processor: AutoImageProcessor,
+ id2label: Mapping[int, str],
+ threshold: float = 0.0,
+ ):
+ """
+ Initialize evaluator with image processor, id2label mapping and threshold for filtering predictions.
+
+ Args:
+ image_processor (AutoImageProcessor): Image processor for
+ `post_process_instance_segmentation` method.
+ id2label (Mapping[int, str]): Mapping from class id to class name.
+ threshold (float): Threshold to filter predicted boxes by confidence. Defaults to 0.0.
+ """
+ self.image_processor = image_processor
+ self.id2label = id2label
+ self.threshold = threshold
+ self.metric = self.get_metric()
+
+ def get_metric(self):
+ metric = MeanAveragePrecision(iou_type="segm", class_metrics=True)
+ return metric
+
+ def reset_metric(self):
+ self.metric.reset()
+
+ def postprocess_target_batch(self, target_batch) -> List[Dict[str, torch.Tensor]]:
+ """Collect targets in a form of list of dictionaries with keys "masks", "labels"."""
+ batch_masks = target_batch[0]
+ batch_labels = target_batch[1]
+ post_processed_targets = []
+ for masks, labels in zip(batch_masks, batch_labels):
+ post_processed_targets.append(
+ {
+ "masks": masks.to(dtype=torch.bool),
+ "labels": labels,
+ }
+ )
+ return post_processed_targets
+
+ def get_target_sizes(self, post_processed_targets) -> List[List[int]]:
+ target_sizes = []
+ for target in post_processed_targets:
+ target_sizes.append(target["masks"].shape[-2:])
+ return target_sizes
+
+ def postprocess_prediction_batch(self, prediction_batch, target_sizes) -> List[Dict[str, torch.Tensor]]:
+ """Collect predictions in a form of list of dictionaries with keys "masks", "labels", "scores"."""
+
+ model_output = ModelOutput(class_queries_logits=prediction_batch[0], masks_queries_logits=prediction_batch[1])
+ post_processed_output = self.image_processor.post_process_instance_segmentation(
+ model_output,
+ threshold=self.threshold,
+ target_sizes=target_sizes,
+ return_binary_maps=True,
+ )
+
+ post_processed_predictions = []
+ for image_predictions, target_size in zip(post_processed_output, target_sizes):
+ if image_predictions["segments_info"]:
+ post_processed_image_prediction = {
+ "masks": image_predictions["segmentation"].to(dtype=torch.bool),
+ "labels": torch.tensor([x["label_id"] for x in image_predictions["segments_info"]]),
+ "scores": torch.tensor([x["score"] for x in image_predictions["segments_info"]]),
+ }
+ else:
+ # for void predictions, we need to provide empty tensors
+ post_processed_image_prediction = {
+ "masks": torch.zeros([0, *target_size], dtype=torch.bool),
+ "labels": torch.tensor([]),
+ "scores": torch.tensor([]),
+ }
+ post_processed_predictions.append(post_processed_image_prediction)
+
+ return post_processed_predictions
+
+ @torch.no_grad()
+ def __call__(self, evaluation_results: EvalPrediction, compute_result: bool = False) -> Mapping[str, float]:
+ """
+ Update metrics with current evaluation results and return metrics if `compute_result` is True.
+
+ Args:
+ evaluation_results (EvalPrediction): Predictions and targets from evaluation.
+ compute_result (bool): Whether to compute and return metrics.
+
+ Returns:
+ Mapping[str, float]: Metrics in a form of dictionary {: }
+ """
+ prediction_batch = nested_cpu(evaluation_results.predictions)
+ target_batch = nested_cpu(evaluation_results.label_ids)
+
+ # For metric computation we need to provide:
+ # - targets in a form of list of dictionaries with keys "masks", "labels"
+ # - predictions in a form of list of dictionaries with keys "masks", "labels", "scores"
+ post_processed_targets = self.postprocess_target_batch(target_batch)
+ target_sizes = self.get_target_sizes(post_processed_targets)
+ post_processed_predictions = self.postprocess_prediction_batch(prediction_batch, target_sizes)
+
+ # Compute metrics
+ self.metric.update(post_processed_predictions, post_processed_targets)
+
+ if not compute_result:
+ return
+
+ metrics = self.metric.compute()
+
+ # Replace list of per class metrics with separate metric for each class
+ classes = metrics.pop("classes")
+ map_per_class = metrics.pop("map_per_class")
+ mar_100_per_class = metrics.pop("mar_100_per_class")
+ for class_id, class_map, class_mar in zip(classes, map_per_class, mar_100_per_class):
+ class_name = self.id2label[class_id.item()] if self.id2label is not None else class_id.item()
+ metrics[f"map_{class_name}"] = class_map
+ metrics[f"mar_100_{class_name}"] = class_mar
+
+ metrics = {k: round(v.item(), 4) for k, v in metrics.items()}
+
+ # Reset metric for next evaluation
+ self.reset_metric()
+
+ return metrics
+
+
+def setup_logging(training_args: TrainingArguments) -> None:
+ """Setup logging according to `training_args`."""
+
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+
+def find_last_checkpoint(training_args: TrainingArguments) -> Optional[str]:
+ """Find the last checkpoint in the output directory according to parameters specified in `training_args`."""
+
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif os.path.isdir(training_args.output_dir) and not training_args.overwrite_output_dir:
+ checkpoint = get_last_checkpoint(training_args.output_dir)
+ if checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ return checkpoint
+
+
+def main():
+ # See all possible arguments in https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments
+ # or by passing the --help flag to this script.
+
+ parser = HfArgumentParser([Arguments, TrainingArguments])
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ args, training_args = parser.parse_args_into_dataclasses()
+
+ # Set default training arguments for instance segmentation
+ training_args.eval_do_concat_batches = False
+ training_args.batch_eval_metrics = True
+ training_args.remove_unused_columns = False
+
+ # # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_instance_segmentation", args)
+
+ # Setup logging and log on each process the small summary:
+ setup_logging(training_args)
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Load last checkpoint from output_dir if it exists (and we are not overwriting it)
+ checkpoint = find_last_checkpoint(training_args)
+
+ # ------------------------------------------------------------------------------------------------
+ # Load dataset, prepare splits
+ # ------------------------------------------------------------------------------------------------
+
+ dataset = load_dataset(args.dataset_name, trust_remote_code=args.trust_remote_code)
+
+ # We need to specify the label2id mapping for the model
+ # it is a mapping from semantic class name to class index.
+ # In case your dataset does not provide it, you can create it manually:
+ # label2id = {"background": 0, "cat": 1, "dog": 2}
+ label2id = dataset["train"][0]["semantic_class_to_id"]
+
+ if args.do_reduce_labels:
+ label2id = {name: idx for name, idx in label2id.items() if idx != 0} # remove background class
+ label2id = {name: idx - 1 for name, idx in label2id.items()} # shift class indices by -1
+
+ id2label = {v: k for k, v in label2id.items()}
+
+ # ------------------------------------------------------------------------------------------------
+ # Load pretrained config, model and image processor
+ # ------------------------------------------------------------------------------------------------
+ model = AutoModelForUniversalSegmentation.from_pretrained(
+ args.model_name_or_path,
+ label2id=label2id,
+ id2label=id2label,
+ ignore_mismatched_sizes=True,
+ token=args.token,
+ )
+
+ image_processor = AutoImageProcessor.from_pretrained(
+ args.model_name_or_path,
+ do_resize=True,
+ size={"height": args.image_height, "width": args.image_width},
+ do_reduce_labels=args.do_reduce_labels,
+ reduce_labels=args.do_reduce_labels, # TODO: remove when mask2former support `do_reduce_labels`
+ token=args.token,
+ )
+
+ # ------------------------------------------------------------------------------------------------
+ # Define image augmentations and dataset transforms
+ # ------------------------------------------------------------------------------------------------
+ train_augment_and_transform = A.Compose(
+ [
+ A.HorizontalFlip(p=0.5),
+ A.RandomBrightnessContrast(p=0.5),
+ A.HueSaturationValue(p=0.1),
+ ],
+ )
+ validation_transform = A.Compose(
+ [A.NoOp()],
+ )
+
+ # Make transform functions for batch and apply for dataset splits
+ train_transform_batch = partial(
+ augment_and_transform_batch, transform=train_augment_and_transform, image_processor=image_processor
+ )
+ validation_transform_batch = partial(
+ augment_and_transform_batch, transform=validation_transform, image_processor=image_processor
+ )
+
+ dataset["train"] = dataset["train"].with_transform(train_transform_batch)
+ dataset["validation"] = dataset["validation"].with_transform(validation_transform_batch)
+
+ # ------------------------------------------------------------------------------------------------
+ # Model training and evaluation with Trainer API
+ # ------------------------------------------------------------------------------------------------
+
+ compute_metrics = Evaluator(image_processor=image_processor, id2label=id2label, threshold=0.0)
+
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=dataset["train"] if training_args.do_train else None,
+ eval_dataset=dataset["validation"] if training_args.do_eval else None,
+ processing_class=image_processor,
+ data_collator=collate_fn,
+ compute_metrics=compute_metrics,
+ )
+
+ # Training
+ if training_args.do_train:
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model()
+ trainer.log_metrics("train", train_result.metrics)
+ trainer.save_metrics("train", train_result.metrics)
+ trainer.save_state()
+
+ # Final evaluation
+ if training_args.do_eval:
+ metrics = trainer.evaluate(eval_dataset=dataset["validation"], metric_key_prefix="test")
+ trainer.log_metrics("test", metrics)
+ trainer.save_metrics("test", metrics)
+
+ # Write model card and (optionally) push to hub
+ kwargs = {
+ "finetuned_from": args.model_name_or_path,
+ "dataset": args.dataset_name,
+ "tags": ["image-segmentation", "instance-segmentation", "vision"],
+ }
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/instance-segmentation/run_instance_segmentation_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/instance-segmentation/run_instance_segmentation_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..e9cd01610bb7b38333b25b214fbb46b989943cc8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/instance-segmentation/run_instance_segmentation_no_trainer.py
@@ -0,0 +1,744 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+
+"""Finetuning 🤗 Transformers model for instance segmentation with Accelerate 🚀."""
+
+import argparse
+import json
+import logging
+import math
+import os
+import sys
+from functools import partial
+from pathlib import Path
+from typing import Any, Mapping
+
+import albumentations as A
+import datasets
+import numpy as np
+import torch
+from accelerate import Accelerator
+from accelerate.utils import set_seed
+from datasets import load_dataset
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from torchmetrics.detection.mean_ap import MeanAveragePrecision
+from tqdm import tqdm
+
+import transformers
+from transformers import (
+ AutoImageProcessor,
+ AutoModelForUniversalSegmentation,
+ SchedulerType,
+ get_scheduler,
+)
+from transformers.image_processing_utils import BatchFeature
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+logger = logging.getLogger(__name__)
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=2.0.0", "To fix: pip install -r examples/pytorch/instance-segmentation/requirements.txt")
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Finetune a transformers model for instance segmentation task")
+
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to a pretrained model or model identifier from huggingface.co/models.",
+ default="facebook/mask2former-swin-tiny-coco-instance",
+ )
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ help="Name of the dataset on the hub.",
+ default="qubvel-hf/ade20k-mini",
+ )
+ parser.add_argument(
+ "--trust_remote_code",
+ action="store_true",
+ help=(
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--image_height",
+ type=int,
+ default=384,
+ help="The height of the images to feed the model.",
+ )
+ parser.add_argument(
+ "--image_width",
+ type=int,
+ default=384,
+ help="The width of the images to feed the model.",
+ )
+ parser.add_argument(
+ "--do_reduce_labels",
+ action="store_true",
+ help="Whether to reduce the number of labels by removing the background class.",
+ )
+ parser.add_argument(
+ "--cache_dir",
+ type=str,
+ help="Path to a folder in which the model and dataset will be cached.",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--dataloader_num_workers",
+ type=int,
+ default=4,
+ help="Number of workers to use for the dataloaders.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument(
+ "--adam_beta1",
+ type=float,
+ default=0.9,
+ help="Beta1 for AdamW optimizer",
+ )
+ parser.add_argument(
+ "--adam_beta2",
+ type=float,
+ default=0.999,
+ help="Beta2 for AdamW optimizer",
+ )
+ parser.add_argument(
+ "--adam_epsilon",
+ type=float,
+ default=1e-8,
+ help="Epsilon for AdamW optimizer",
+ )
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ required=False,
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+ if args.push_to_hub or args.with_tracking:
+ if args.output_dir is None:
+ raise ValueError(
+ "Need an `output_dir` to create a repo when `--push_to_hub` or `with_tracking` is specified."
+ )
+
+ if args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+
+ return args
+
+
+def augment_and_transform_batch(
+ examples: Mapping[str, Any], transform: A.Compose, image_processor: AutoImageProcessor
+) -> BatchFeature:
+ batch = {
+ "pixel_values": [],
+ "mask_labels": [],
+ "class_labels": [],
+ }
+
+ for pil_image, pil_annotation in zip(examples["image"], examples["annotation"]):
+ image = np.array(pil_image)
+ semantic_and_instance_masks = np.array(pil_annotation)[..., :2]
+
+ # Apply augmentations
+ output = transform(image=image, mask=semantic_and_instance_masks)
+
+ aug_image = output["image"]
+ aug_semantic_and_instance_masks = output["mask"]
+ aug_instance_mask = aug_semantic_and_instance_masks[..., 1]
+
+ # Create mapping from instance id to semantic id
+ unique_semantic_id_instance_id_pairs = np.unique(aug_semantic_and_instance_masks.reshape(-1, 2), axis=0)
+ instance_id_to_semantic_id = {
+ instance_id: semantic_id for semantic_id, instance_id in unique_semantic_id_instance_id_pairs
+ }
+
+ # Apply the image processor transformations: resizing, rescaling, normalization
+ model_inputs = image_processor(
+ images=[aug_image],
+ segmentation_maps=[aug_instance_mask],
+ instance_id_to_semantic_id=instance_id_to_semantic_id,
+ return_tensors="pt",
+ )
+
+ batch["pixel_values"].append(model_inputs.pixel_values[0])
+ batch["mask_labels"].append(model_inputs.mask_labels[0])
+ batch["class_labels"].append(model_inputs.class_labels[0])
+
+ return batch
+
+
+def collate_fn(examples):
+ batch = {}
+ batch["pixel_values"] = torch.stack([example["pixel_values"] for example in examples])
+ batch["class_labels"] = [example["class_labels"] for example in examples]
+ batch["mask_labels"] = [example["mask_labels"] for example in examples]
+ if "pixel_mask" in examples[0]:
+ batch["pixel_mask"] = torch.stack([example["pixel_mask"] for example in examples])
+ return batch
+
+
+def nested_cpu(tensors):
+ if isinstance(tensors, (list, tuple)):
+ return type(tensors)(nested_cpu(t) for t in tensors)
+ elif isinstance(tensors, Mapping):
+ return type(tensors)({k: nested_cpu(t) for k, t in tensors.items()})
+ elif isinstance(tensors, torch.Tensor):
+ return tensors.cpu().detach()
+ else:
+ return tensors
+
+
+def evaluation_loop(model, image_processor, accelerator: Accelerator, dataloader, id2label):
+ metric = MeanAveragePrecision(iou_type="segm", class_metrics=True)
+
+ for inputs in tqdm(dataloader, total=len(dataloader), disable=not accelerator.is_local_main_process):
+ with torch.no_grad():
+ outputs = model(**inputs)
+
+ inputs = accelerator.gather_for_metrics(inputs)
+ inputs = nested_cpu(inputs)
+
+ outputs = accelerator.gather_for_metrics(outputs)
+ outputs = nested_cpu(outputs)
+
+ # For metric computation we need to provide:
+ # - targets in a form of list of dictionaries with keys "masks", "labels"
+ # - predictions in a form of list of dictionaries with keys "masks", "labels", "scores"
+
+ post_processed_targets = []
+ post_processed_predictions = []
+ target_sizes = []
+
+ # Collect targets
+ for masks, labels in zip(inputs["mask_labels"], inputs["class_labels"]):
+ post_processed_targets.append(
+ {
+ "masks": masks.to(dtype=torch.bool),
+ "labels": labels,
+ }
+ )
+ target_sizes.append(masks.shape[-2:])
+
+ # Collect predictions
+ post_processed_output = image_processor.post_process_instance_segmentation(
+ outputs,
+ threshold=0.0,
+ target_sizes=target_sizes,
+ return_binary_maps=True,
+ )
+
+ for image_predictions, target_size in zip(post_processed_output, target_sizes):
+ if image_predictions["segments_info"]:
+ post_processed_image_prediction = {
+ "masks": image_predictions["segmentation"].to(dtype=torch.bool),
+ "labels": torch.tensor([x["label_id"] for x in image_predictions["segments_info"]]),
+ "scores": torch.tensor([x["score"] for x in image_predictions["segments_info"]]),
+ }
+ else:
+ # for void predictions, we need to provide empty tensors
+ post_processed_image_prediction = {
+ "masks": torch.zeros([0, *target_size], dtype=torch.bool),
+ "labels": torch.tensor([]),
+ "scores": torch.tensor([]),
+ }
+ post_processed_predictions.append(post_processed_image_prediction)
+
+ # Update metric for batch targets and predictions
+ metric.update(post_processed_predictions, post_processed_targets)
+
+ # Compute metrics
+ metrics = metric.compute()
+
+ # Replace list of per class metrics with separate metric for each class
+ classes = metrics.pop("classes")
+ map_per_class = metrics.pop("map_per_class")
+ mar_100_per_class = metrics.pop("mar_100_per_class")
+ for class_id, class_map, class_mar in zip(classes, map_per_class, mar_100_per_class):
+ class_name = id2label[class_id.item()] if id2label is not None else class_id.item()
+ metrics[f"map_{class_name}"] = class_map
+ metrics[f"mar_100_{class_name}"] = class_mar
+
+ metrics = {k: round(v.item(), 4) for k, v in metrics.items()}
+
+ return metrics
+
+
+def setup_logging(accelerator: Accelerator) -> None:
+ """Setup logging according to `training_args`."""
+
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ logger.setLevel(logging.INFO)
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+
+def handle_repository_creation(accelerator: Accelerator, args: argparse.Namespace):
+ """Create a repository for the model and dataset if `args.push_to_hub` is set."""
+
+ repo_id = None
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ return repo_id
+
+
+def main():
+ args = parse_args()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_instance_segmentation_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+ accelerator_log_kwargs = {}
+
+ if args.with_tracking:
+ accelerator_log_kwargs["log_with"] = args.report_to
+ accelerator_log_kwargs["project_dir"] = args.output_dir
+
+ accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
+ setup_logging(accelerator)
+
+ # If passed along, set the training seed now.
+ # We set device_specific to True as we want different data augmentation per device.
+ if args.seed is not None:
+ set_seed(args.seed, device_specific=True)
+
+ # Create repository if push ot hub is specified
+ repo_id = handle_repository_creation(accelerator, args)
+
+ if args.push_to_hub:
+ api = HfApi()
+
+ # ------------------------------------------------------------------------------------------------
+ # Load dataset, prepare splits
+ # ------------------------------------------------------------------------------------------------
+
+ # In distributed training, the load_dataset function guarantees that only one local process can concurrently
+ # download the dataset.
+ dataset = load_dataset(args.dataset_name, cache_dir=args.cache_dir, trust_remote_code=args.trust_remote_code)
+
+ # We need to specify the label2id mapping for the model
+ # it is a mapping from semantic class name to class index.
+ # In case your dataset does not provide it, you can create it manually:
+ # label2id = {"background": 0, "cat": 1, "dog": 2}
+ label2id = dataset["train"][0]["semantic_class_to_id"]
+
+ if args.do_reduce_labels:
+ label2id = {name: idx for name, idx in label2id.items() if idx != 0} # remove background class
+ label2id = {name: idx - 1 for name, idx in label2id.items()} # shift class indices by -1
+
+ id2label = {v: k for k, v in label2id.items()}
+
+ # ------------------------------------------------------------------------------------------------
+ # Load pretrained model and image processor
+ # ------------------------------------------------------------------------------------------------
+ model = AutoModelForUniversalSegmentation.from_pretrained(
+ args.model_name_or_path,
+ label2id=label2id,
+ id2label=id2label,
+ ignore_mismatched_sizes=True,
+ token=args.hub_token,
+ )
+
+ image_processor = AutoImageProcessor.from_pretrained(
+ args.model_name_or_path,
+ do_resize=True,
+ size={"height": args.image_height, "width": args.image_width},
+ do_reduce_labels=args.do_reduce_labels,
+ reduce_labels=args.do_reduce_labels, # TODO: remove when mask2former support `do_reduce_labels`
+ token=args.hub_token,
+ )
+
+ # ------------------------------------------------------------------------------------------------
+ # Define image augmentations and dataset transforms
+ # ------------------------------------------------------------------------------------------------
+ train_augment_and_transform = A.Compose(
+ [
+ A.HorizontalFlip(p=0.5),
+ A.RandomBrightnessContrast(p=0.5),
+ A.HueSaturationValue(p=0.1),
+ ],
+ )
+ validation_transform = A.Compose(
+ [A.NoOp()],
+ )
+
+ # Make transform functions for batch and apply for dataset splits
+ train_transform_batch = partial(
+ augment_and_transform_batch, transform=train_augment_and_transform, image_processor=image_processor
+ )
+ validation_transform_batch = partial(
+ augment_and_transform_batch, transform=validation_transform, image_processor=image_processor
+ )
+
+ with accelerator.main_process_first():
+ dataset["train"] = dataset["train"].with_transform(train_transform_batch)
+ dataset["validation"] = dataset["validation"].with_transform(validation_transform_batch)
+
+ dataloader_common_args = {
+ "num_workers": args.dataloader_num_workers,
+ "persistent_workers": True,
+ "collate_fn": collate_fn,
+ }
+ train_dataloader = DataLoader(
+ dataset["train"], shuffle=True, batch_size=args.per_device_train_batch_size, **dataloader_common_args
+ )
+ valid_dataloader = DataLoader(
+ dataset["validation"], shuffle=False, batch_size=args.per_device_eval_batch_size, **dataloader_common_args
+ )
+
+ # ------------------------------------------------------------------------------------------------
+ # Define optimizer, scheduler and prepare everything with the accelerator
+ # ------------------------------------------------------------------------------------------------
+
+ # Optimizer
+ optimizer = torch.optim.AdamW(
+ list(model.parameters()),
+ lr=args.learning_rate,
+ betas=[args.adam_beta1, args.adam_beta2],
+ eps=args.adam_epsilon,
+ )
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
+ num_training_steps=args.max_train_steps
+ if overrode_max_train_steps
+ else args.max_train_steps * accelerator.num_processes,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, valid_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, valid_dataloader, lr_scheduler
+ )
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("instance_segmentation_no_trainer", experiment_config)
+
+ # ------------------------------------------------------------------------------------------------
+ # Run training with evaluation on each epoch
+ # ------------------------------------------------------------------------------------------------
+
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(dataset['train'])}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ checkpoint_path = args.resume_from_checkpoint
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ checkpoint_path = path
+ path = os.path.basename(checkpoint_path)
+
+ accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
+ accelerator.load_state(checkpoint_path)
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ completed_steps = resume_step // args.gradient_accumulation_steps
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We skip the first `n` batches in the dataloader when resuming from a checkpoint
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+
+ for step, batch in enumerate(active_dataloader):
+ with accelerator.accumulate(model):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # Checks if the accelerator has performed an optimization step behind the scenes
+ if accelerator.sync_gradients:
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir,
+ is_main_process=accelerator.is_main_process,
+ save_function=accelerator.save,
+ )
+ if accelerator.is_main_process:
+ image_processor.save_pretrained(args.output_dir)
+ api.upload_folder(
+ repo_id=repo_id,
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if completed_steps >= args.max_train_steps:
+ break
+
+ logger.info("***** Running evaluation *****")
+ metrics = evaluation_loop(model, image_processor, accelerator, valid_dataloader, id2label)
+
+ logger.info(f"epoch {epoch}: {metrics}")
+
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "train_loss": total_loss.item() / len(train_dataloader),
+ **metrics,
+ "epoch": epoch,
+ "step": completed_steps,
+ },
+ step=completed_steps,
+ )
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ image_processor.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if args.checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ # ------------------------------------------------------------------------------------------------
+ # Run evaluation on test dataset and save the model
+ # ------------------------------------------------------------------------------------------------
+
+ logger.info("***** Running evaluation on test dataset *****")
+ metrics = evaluation_loop(model, image_processor, accelerator, valid_dataloader, id2label)
+ metrics = {f"test_{k}": v for k, v in metrics.items()}
+
+ logger.info(f"Test metrics: {metrics}")
+
+ if args.with_tracking:
+ accelerator.end_training()
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ with open(os.path.join(args.output_dir, "all_results.json"), "w") as f:
+ json.dump(metrics, f, indent=2)
+
+ image_processor.save_pretrained(args.output_dir)
+
+ if args.push_to_hub:
+ api.upload_folder(
+ commit_message="End of training",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ ignore_patterns=["epoch_*"],
+ )
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..b13cebde5f579650c3f8a4b62bbd805de9984a31
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/README.md
@@ -0,0 +1,246 @@
+
+
+## Language model training
+
+Fine-tuning (or training from scratch) the library models for language modeling on a text dataset for GPT, GPT-2,
+ALBERT, BERT, DistilBERT, RoBERTa, XLNet... GPT and GPT-2 are trained or fine-tuned using a causal language modeling
+(CLM) loss while ALBERT, BERT, DistilBERT and RoBERTa are trained or fine-tuned using a masked language modeling (MLM)
+loss. XLNet uses permutation language modeling (PLM), you can find more information about the differences between those
+objectives in our [model summary](https://huggingface.co/transformers/model_summary.html).
+
+There are two sets of scripts provided. The first set leverages the Trainer API. The second set with `no_trainer` in the suffix uses a custom training loop and leverages the 🤗 Accelerate library . Both sets use the 🤗 Datasets library. You can easily customize them to your needs if you need extra processing on your datasets.
+
+**Note:** The old script `run_language_modeling.py` is still available [here](https://github.com/huggingface/transformers/blob/main/examples/legacy/run_language_modeling.py).
+
+The following examples, will run on datasets hosted on our [hub](https://huggingface.co/datasets) or with your own
+text files for training and validation. We give examples of both below.
+
+### GPT-2/GPT and causal language modeling
+
+The following example fine-tunes GPT-2 on WikiText-2. We're using the raw WikiText-2 (no tokens were replaced before
+the tokenization). The loss here is that of causal language modeling.
+
+```bash
+python run_clm.py \
+ --model_name_or_path openai-community/gpt2 \
+ --dataset_name wikitext \
+ --dataset_config_name wikitext-2-raw-v1 \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 8 \
+ --do_train \
+ --do_eval \
+ --output_dir /tmp/test-clm
+```
+
+This takes about half an hour to train on a single K80 GPU and about one minute for the evaluation to run. It reaches
+a score of ~20 perplexity once fine-tuned on the dataset.
+
+To run on your own training and validation files, use the following command:
+
+```bash
+python run_clm.py \
+ --model_name_or_path openai-community/gpt2 \
+ --train_file path_to_train_file \
+ --validation_file path_to_validation_file \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 8 \
+ --do_train \
+ --do_eval \
+ --output_dir /tmp/test-clm
+```
+
+This uses the built in HuggingFace `Trainer` for training. If you want to use a custom training loop, you can utilize or adapt the `run_clm_no_trainer.py` script. Take a look at the script for a list of supported arguments. An example is shown below:
+
+```bash
+python run_clm_no_trainer.py \
+ --dataset_name wikitext \
+ --dataset_config_name wikitext-2-raw-v1 \
+ --model_name_or_path openai-community/gpt2 \
+ --output_dir /tmp/test-clm
+```
+
+### GPT-2/GPT and causal language modeling with fill-in-the middle objective
+
+The following example fine-tunes GPT-2 on WikiText-2 but using the Fill-in-middle training objective. FIM objective was proposed in [Efficient Training of Language Models to Fill in the Middle](https://arxiv.org/abs/2207.14255). They showed that autoregressive language models can learn to infill text after applying a straightforward transformation to the dataset, which simply moves a span of text from the middle of a document to its end.
+
+We're using the raw WikiText-2 (no tokens were replaced before the tokenization). The loss here is that of causal language modeling.
+
+```bash
+python run_fim.py \
+ --model_name_or_path gpt2 \
+ --dataset_name wikitext \
+ --dataset_config_name wikitext-2-raw-v1 \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 8 \
+ --fim_rate 0.5 \
+ --fim_spm_rate 0.2 \
+ --do_train \
+ --do_eval \
+ --output_dir /tmp/test-clm
+```
+
+To run on your own training and validation files, use the following command:
+
+```bash
+python run_fim.py \
+ --model_name_or_path gpt2 \
+ --train_file path_to_train_file \
+ --validation_file path_to_validation_file \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 8 \
+ --fim_rate 0.5 \
+ --fim_spm_rate 0.2 \
+ --do_train \
+ --do_eval \
+ --output_dir /tmp/test-clm
+```
+
+This uses the built in HuggingFace `Trainer` for training. If you want to use a custom training loop, you can utilize or adapt the `run_fim_no_trainer.py` script. Take a look at the script for a list of supported arguments. An example is shown below:
+
+```bash
+python run_fim_no_trainer.py \
+ --model_name_or_path gpt2 \
+ --dataset_name wikitext \
+ --dataset_config_name wikitext-2-raw-v1 \
+ --model_name_or_path gpt2 \
+ --fim_rate 0.5 \
+ --fim_spm_rate 0.2 \
+ --output_dir /tmp/test-clm
+```
+
+**Note**: Passing in FIM rate as `0.5` means that FIM transformations will be applied to the dataset with a probability of 50%. Whereas passing in FIM SPM rate as `0.2` means that 20% of FIM transformations will use SPM (or Suffix-Prefix-Middle) and the remaining 80% will use PSM (or Prefix-Suffix-Middle) mode of transformation.
+
+### RoBERTa/BERT/DistilBERT and masked language modeling
+
+The following example fine-tunes RoBERTa on WikiText-2. Here too, we're using the raw WikiText-2. The loss is different
+as BERT/RoBERTa have a bidirectional mechanism; we're therefore using the same loss that was used during their
+pre-training: masked language modeling.
+
+In accordance to the RoBERTa paper, we use dynamic masking rather than static masking. The model may, therefore,
+converge slightly slower (over-fitting takes more epochs).
+
+```bash
+python run_mlm.py \
+ --model_name_or_path FacebookAI/roberta-base \
+ --dataset_name wikitext \
+ --dataset_config_name wikitext-2-raw-v1 \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 8 \
+ --do_train \
+ --do_eval \
+ --output_dir /tmp/test-mlm
+```
+
+To run on your own training and validation files, use the following command:
+
+```bash
+python run_mlm.py \
+ --model_name_or_path FacebookAI/roberta-base \
+ --train_file path_to_train_file \
+ --validation_file path_to_validation_file \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 8 \
+ --do_train \
+ --do_eval \
+ --output_dir /tmp/test-mlm
+```
+
+If your dataset is organized with one sample per line, you can use the `--line_by_line` flag (otherwise the script
+concatenates all texts and then splits them in blocks of the same length).
+
+This uses the built in HuggingFace `Trainer` for training. If you want to use a custom training loop, you can utilize or adapt the `run_mlm_no_trainer.py` script. Take a look at the script for a list of supported arguments. An example is shown below:
+
+```bash
+python run_mlm_no_trainer.py \
+ --dataset_name wikitext \
+ --dataset_config_name wikitext-2-raw-v1 \
+ --model_name_or_path FacebookAI/roberta-base \
+ --output_dir /tmp/test-mlm
+```
+
+**Note:** On TPU, you should use the flag `--pad_to_max_length` in conjunction with the `--line_by_line` flag to make
+sure all your batches have the same length.
+
+### Whole word masking
+
+This part was moved to `examples/research_projects/mlm_wwm`.
+
+### XLNet and permutation language modeling
+
+XLNet uses a different training objective, which is permutation language modeling. It is an autoregressive method
+to learn bidirectional contexts by maximizing the expected likelihood over all permutations of the input
+sequence factorization order.
+
+We use the `--plm_probability` flag to define the ratio of length of a span of masked tokens to surrounding
+context length for permutation language modeling.
+
+The `--max_span_length` flag may also be used to limit the length of a span of masked tokens used
+for permutation language modeling.
+
+Here is how to fine-tune XLNet on wikitext-2:
+
+```bash
+python run_plm.py \
+ --model_name_or_path=xlnet/xlnet-base-cased \
+ --dataset_name wikitext \
+ --dataset_config_name wikitext-2-raw-v1 \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 8 \
+ --do_train \
+ --do_eval \
+ --output_dir /tmp/test-plm
+```
+
+To fine-tune it on your own training and validation file, run:
+
+```bash
+python run_plm.py \
+ --model_name_or_path=xlnet/xlnet-base-cased \
+ --train_file path_to_train_file \
+ --validation_file path_to_validation_file \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 8 \
+ --do_train \
+ --do_eval \
+ --output_dir /tmp/test-plm
+```
+
+If your dataset is organized with one sample per line, you can use the `--line_by_line` flag (otherwise the script
+concatenates all texts and then splits them in blocks of the same length).
+
+**Note:** On TPU, you should use the flag `--pad_to_max_length` in conjunction with the `--line_by_line` flag to make
+sure all your batches have the same length.
+
+## Streaming
+
+To use the streaming dataset mode which can be very useful for large datasets, add `--streaming` to the command line. This is supported by `run_mlm.py`, `run_clm.py` and `run_fim.py`. Make sure to adapt the other scripts to your use case by taking inspiration from them.
+
+## Low Cpu Memory Usage
+
+To use low cpu memory mode which can be very useful for LLM, add `--low_cpu_mem_usage` to the command line. This is currently supported by `run_clm.py`,`run_mlm.py`, `run_plm.py`, `run_fim.py`, `run_mlm_no_trainer.py`, `run_clm_no_trainer.py` and `run_fim_no_trainer.py`.
+
+## Creating a model on the fly
+
+When training a model from scratch, configuration values may be overridden with the help of `--config_overrides`:
+
+
+```bash
+python run_clm.py --model_type gpt2 --tokenizer_name openai-community/gpt2 \ --config_overrides="n_embd=1024,n_head=16,n_layer=48,n_positions=102" \
+[...]
+```
+
+This feature is only available in `run_clm.py`, `run_plm.py`, `run_mlm.py` and `run_fim.py`.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..851e8de09ccdc1f58eb698d63419a98bf53623cc
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/requirements.txt
@@ -0,0 +1,7 @@
+accelerate >= 0.12.0
+torch >= 1.3
+datasets >= 2.14.0
+sentencepiece != 0.1.92
+protobuf
+evaluate
+scikit-learn
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_clm.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_clm.py
new file mode 100644
index 0000000000000000000000000000000000000000..54098f5a7dd617f3b3179f3521f7e8d6fd57d245
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_clm.py
@@ -0,0 +1,657 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2020 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for causal language modeling (GPT, GPT-2, CTRL, ...) on a text file or a dataset.
+
+Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
+https://huggingface.co/models?filter=text-generation
+"""
+# You can also adapt this script on your own causal language modeling task. Pointers for this are left as comments.
+
+import logging
+import math
+import os
+import sys
+from dataclasses import dataclass, field
+from itertools import chain
+from typing import Optional
+
+import datasets
+import evaluate
+import torch
+from datasets import load_dataset
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ MODEL_FOR_CAUSAL_LM_MAPPING,
+ AutoConfig,
+ AutoModelForCausalLM,
+ AutoTokenizer,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ default_data_collator,
+ is_torch_xla_available,
+ set_seed,
+)
+from transformers.testing_utils import CaptureLogger
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
+
+logger = logging.getLogger(__name__)
+
+
+MODEL_CONFIG_CLASSES = list(MODEL_FOR_CAUSAL_LM_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ model_name_or_path: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
+ )
+ },
+ )
+ model_type: Optional[str] = field(
+ default=None,
+ metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
+ )
+ config_overrides: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Override some existing default config settings when a model is trained from scratch. Example: "
+ "n_embd=10,resid_pdrop=0.2,scale_attn_weights=false,summary_type=cls_index"
+ )
+ },
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ torch_dtype: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Override the default `torch.dtype` and load the model under this dtype. If `auto` is passed, the "
+ "dtype will be automatically derived from the model's weights."
+ ),
+ "choices": ["auto", "bfloat16", "float16", "float32"],
+ },
+ )
+ low_cpu_mem_usage: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "It is an option to create the model as an empty shell, then only materialize its parameters when the pretrained weights are loaded. "
+ "set True will benefit LLM loading time and RAM consumption."
+ )
+ },
+ )
+
+ def __post_init__(self):
+ if self.config_overrides is not None and (self.config_name is not None or self.model_name_or_path is not None):
+ raise ValueError(
+ "--config_overrides can't be used in combination with --config_name or --model_name_or_path"
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ streaming: bool = field(default=False, metadata={"help": "Enable streaming mode"})
+ block_size: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Optional input sequence length after tokenization. "
+ "The training dataset will be truncated in block of this size for training. "
+ "Default to the model max input length for single sentence inputs (take into account special tokens)."
+ )
+ },
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ validation_split_percentage: Optional[int] = field(
+ default=5,
+ metadata={
+ "help": "The percentage of the train set used as validation set in case there's no validation split"
+ },
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ keep_linebreaks: bool = field(
+ default=True, metadata={"help": "Whether to keep line breaks when using TXT files or not."}
+ )
+
+ def __post_init__(self):
+ if self.streaming:
+ require_version("datasets>=2.0.0", "The streaming feature requires `datasets>=2.0.0`")
+
+ if self.dataset_name is None and self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, a json or a txt file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, a json or a txt file."
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_clm", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ datasets.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ streaming=data_args.streaming,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ streaming=data_args.streaming,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ raw_datasets["train"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ streaming=data_args.streaming,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ dataset_args = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = (
+ data_args.train_file.split(".")[-1]
+ if data_args.train_file is not None
+ else data_args.validation_file.split(".")[-1]
+ )
+ if extension == "txt":
+ extension = "text"
+ dataset_args["keep_linebreaks"] = data_args.keep_linebreaks
+ raw_datasets = load_dataset(
+ extension,
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ **dataset_args,
+ )
+ # If no validation data is there, validation_split_percentage will be used to divide the dataset.
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ **dataset_args,
+ )
+ raw_datasets["train"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ **dataset_args,
+ )
+
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+
+ config_kwargs = {
+ "cache_dir": model_args.cache_dir,
+ "revision": model_args.model_revision,
+ "token": model_args.token,
+ "trust_remote_code": model_args.trust_remote_code,
+ }
+ if model_args.config_name:
+ config = AutoConfig.from_pretrained(model_args.config_name, **config_kwargs)
+ elif model_args.model_name_or_path:
+ config = AutoConfig.from_pretrained(model_args.model_name_or_path, **config_kwargs)
+ else:
+ config = CONFIG_MAPPING[model_args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+ if model_args.config_overrides is not None:
+ logger.info(f"Overriding config: {model_args.config_overrides}")
+ config.update_from_string(model_args.config_overrides)
+ logger.info(f"New config: {config}")
+
+ tokenizer_kwargs = {
+ "cache_dir": model_args.cache_dir,
+ "use_fast": model_args.use_fast_tokenizer,
+ "revision": model_args.model_revision,
+ "token": model_args.token,
+ "trust_remote_code": model_args.trust_remote_code,
+ }
+ if model_args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(model_args.tokenizer_name, **tokenizer_kwargs)
+ elif model_args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(model_args.model_name_or_path, **tokenizer_kwargs)
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if model_args.model_name_or_path:
+ torch_dtype = (
+ model_args.torch_dtype
+ if model_args.torch_dtype in ["auto", None]
+ else getattr(torch, model_args.torch_dtype)
+ )
+ model = AutoModelForCausalLM.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ torch_dtype=torch_dtype,
+ low_cpu_mem_usage=model_args.low_cpu_mem_usage,
+ )
+ else:
+ model = AutoModelForCausalLM.from_config(config, trust_remote_code=model_args.trust_remote_code)
+ n_params = sum({p.data_ptr(): p.numel() for p in model.parameters()}.values())
+ logger.info(f"Training new model from scratch - Total size={n_params/2**20:.2f}M params")
+
+ # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
+ # on a small vocab and want a smaller embedding size, remove this test.
+ embedding_size = model.get_input_embeddings().weight.shape[0]
+ if len(tokenizer) > embedding_size:
+ model.resize_token_embeddings(len(tokenizer))
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ if training_args.do_train:
+ column_names = list(raw_datasets["train"].features)
+ else:
+ column_names = list(raw_datasets["validation"].features)
+ text_column_name = "text" if "text" in column_names else column_names[0]
+
+ # since this will be pickled to avoid _LazyModule error in Hasher force logger loading before tokenize_function
+ tok_logger = transformers.utils.logging.get_logger("transformers.tokenization_utils_base")
+
+ def tokenize_function(examples):
+ with CaptureLogger(tok_logger) as cl:
+ output = tokenizer(examples[text_column_name])
+ # clm input could be much much longer than block_size
+ if "Token indices sequence length is longer than the" in cl.out:
+ tok_logger.warning(
+ "^^^^^^^^^^^^^^^^ Please ignore the warning above - this long input will be chunked into smaller bits"
+ " before being passed to the model."
+ )
+ return output
+
+ with training_args.main_process_first(desc="dataset map tokenization"):
+ if not data_args.streaming:
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on dataset",
+ )
+ else:
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=column_names,
+ )
+ if hasattr(config, "max_position_embeddings"):
+ max_pos_embeddings = config.max_position_embeddings
+ else:
+ # Define a default value if the attribute is missing in the config.
+ max_pos_embeddings = 1024
+
+ if data_args.block_size is None:
+ block_size = tokenizer.model_max_length
+ if block_size > max_pos_embeddings:
+ logger.warning(
+ f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
+ f"Using block_size={min(1024, max_pos_embeddings)} instead. You can change that default value by passing --block_size xxx."
+ )
+ if max_pos_embeddings > 0:
+ block_size = min(1024, max_pos_embeddings)
+ else:
+ block_size = 1024
+ else:
+ if data_args.block_size > tokenizer.model_max_length:
+ logger.warning(
+ f"The block_size passed ({data_args.block_size}) is larger than the maximum length for the model "
+ f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
+ )
+ block_size = min(data_args.block_size, tokenizer.model_max_length)
+
+ # Main data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
+ def group_texts(examples):
+ # Concatenate all texts.
+ concatenated_examples = {k: list(chain(*examples[k])) for k in examples.keys()}
+ total_length = len(concatenated_examples[list(examples.keys())[0]])
+ # We drop the small remainder, and if the total_length < block_size we exclude this batch and return an empty dict.
+ # We could add padding if the model supported it instead of this drop, you can customize this part to your needs.
+ total_length = (total_length // block_size) * block_size
+ # Split by chunks of max_len.
+ result = {
+ k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
+ for k, t in concatenated_examples.items()
+ }
+ result["labels"] = result["input_ids"].copy()
+ return result
+
+ # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
+ # for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
+ # to preprocess.
+ #
+ # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
+ # https://huggingface.co/docs/datasets/process#map
+
+ with training_args.main_process_first(desc="grouping texts together"):
+ if not data_args.streaming:
+ lm_datasets = tokenized_datasets.map(
+ group_texts,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc=f"Grouping texts in chunks of {block_size}",
+ )
+ else:
+ lm_datasets = tokenized_datasets.map(
+ group_texts,
+ batched=True,
+ )
+
+ if training_args.do_train:
+ if "train" not in tokenized_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = lm_datasets["train"]
+ if data_args.max_train_samples is not None:
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+
+ if training_args.do_eval:
+ if "validation" not in tokenized_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_dataset = lm_datasets["validation"]
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+
+ def preprocess_logits_for_metrics(logits, labels):
+ if isinstance(logits, tuple):
+ # Depending on the model and config, logits may contain extra tensors,
+ # like past_key_values, but logits always come first
+ logits = logits[0]
+ return logits.argmax(dim=-1)
+
+ metric = evaluate.load("accuracy", cache_dir=model_args.cache_dir)
+
+ def compute_metrics(eval_preds):
+ preds, labels = eval_preds
+ # preds have the same shape as the labels, after the argmax(-1) has been calculated
+ # by preprocess_logits_for_metrics but we need to shift the labels
+ labels = labels[:, 1:].reshape(-1)
+ preds = preds[:, :-1].reshape(-1)
+ return metric.compute(predictions=preds, references=labels)
+
+ # Initialize our Trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset if training_args.do_train else None,
+ eval_dataset=eval_dataset if training_args.do_eval else None,
+ processing_class=tokenizer,
+ # Data collator will default to DataCollatorWithPadding, so we change it.
+ data_collator=default_data_collator,
+ compute_metrics=compute_metrics if training_args.do_eval and not is_torch_xla_available() else None,
+ preprocess_logits_for_metrics=preprocess_logits_for_metrics
+ if training_args.do_eval and not is_torch_xla_available()
+ else None,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model() # Saves the tokenizer too for easy upload
+
+ metrics = train_result.metrics
+
+ max_train_samples = (
+ data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
+ )
+ metrics["train_samples"] = min(max_train_samples, len(train_dataset))
+
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+
+ metrics = trainer.evaluate()
+
+ max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
+ metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
+ try:
+ perplexity = math.exp(metrics["eval_loss"])
+ except OverflowError:
+ perplexity = float("inf")
+ metrics["perplexity"] = perplexity
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "text-generation"}
+ if data_args.dataset_name is not None:
+ kwargs["dataset_tags"] = data_args.dataset_name
+ if data_args.dataset_config_name is not None:
+ kwargs["dataset_args"] = data_args.dataset_config_name
+ kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
+ else:
+ kwargs["dataset"] = data_args.dataset_name
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_clm_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_clm_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..e35e4e7d907ecb810e0388e834196677d52645e1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_clm_no_trainer.py
@@ -0,0 +1,725 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for causal language modeling (GPT, GPT-2, CTRL, ...)
+on a text file or a dataset without using HuggingFace Trainer.
+
+Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
+https://huggingface.co/models?filter=text-generation
+"""
+# You can also adapt this script on your own causal language modeling task. Pointers for this are left as comments.
+
+import argparse
+import json
+import logging
+import math
+import os
+import random
+from itertools import chain
+from pathlib import Path
+
+import datasets
+import torch
+from accelerate import Accelerator, DistributedType
+from accelerate.logging import get_logger
+from accelerate.utils import set_seed
+from datasets import load_dataset
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from tqdm.auto import tqdm
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ MODEL_MAPPING,
+ AutoConfig,
+ AutoModelForCausalLM,
+ AutoTokenizer,
+ SchedulerType,
+ default_data_collator,
+ get_scheduler,
+)
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+logger = get_logger(__name__)
+
+require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
+
+MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Finetune a transformers model on a causal language modeling task")
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ default=None,
+ help="The name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--dataset_config_name",
+ type=str,
+ default=None,
+ help="The configuration name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--train_file", type=str, default=None, help="A csv, txt or a json file containing the training data."
+ )
+ parser.add_argument(
+ "--validation_file", type=str, default=None, help="A csv, txt or a json file containing the validation data."
+ )
+ parser.add_argument(
+ "--validation_split_percentage",
+ default=5,
+ help="The percentage of the train set used as validation set in case there's no validation split",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=False,
+ )
+ parser.add_argument(
+ "--config_name",
+ type=str,
+ default=None,
+ help="Pretrained config name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ type=str,
+ default=None,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--use_slow_tokenizer",
+ action="store_true",
+ help="If passed, will use a slow tokenizer (not backed by the 🤗 Tokenizers library).",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument(
+ "--model_type",
+ type=str,
+ default=None,
+ help="Model type to use if training from scratch.",
+ choices=MODEL_TYPES,
+ )
+ parser.add_argument(
+ "--block_size",
+ type=int,
+ default=None,
+ help=(
+ "Optional input sequence length after tokenization. The training dataset will be truncated in block of"
+ " this size for training. Default to the model max input length for single sentence inputs (take into"
+ " account special tokens)."
+ ),
+ )
+ parser.add_argument(
+ "--preprocessing_num_workers",
+ type=int,
+ default=None,
+ help="The number of processes to use for the preprocessing.",
+ )
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+ parser.add_argument(
+ "--no_keep_linebreaks", action="store_true", help="Do not keep line breaks when using TXT files."
+ )
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--trust_remote_code",
+ action="store_true",
+ help=(
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ parser.add_argument(
+ "--low_cpu_mem_usage",
+ action="store_true",
+ help=(
+ "It is an option to create the model as an empty shell, then only materialize its parameters when the pretrained weights are loaded. "
+ "If passed, LLM loading time and RAM consumption will be benefited."
+ ),
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+ if args.dataset_name is None and args.train_file is None and args.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if args.train_file is not None:
+ extension = args.train_file.split(".")[-1]
+ if extension not in ["csv", "json", "txt"]:
+ raise ValueError("`train_file` should be a csv, json or txt file.")
+ if args.validation_file is not None:
+ extension = args.validation_file.split(".")[-1]
+ if extension not in ["csv", "json", "txt"]:
+ raise ValueError("`validation_file` should be a csv, json or txt file.")
+
+ if args.push_to_hub:
+ if args.output_dir is None:
+ raise ValueError("Need an `output_dir` to create a repo when `--push_to_hub` is passed.")
+
+ return args
+
+
+def main():
+ args = parse_args()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_clm_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+ accelerator_log_kwargs = {}
+
+ if args.with_tracking:
+ accelerator_log_kwargs["log_with"] = args.report_to
+ accelerator_log_kwargs["project_dir"] = args.output_dir
+
+ accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
+ )
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ args.dataset_name,
+ args.dataset_config_name,
+ split=f"train[:{args.validation_split_percentage}%]",
+ trust_remote_code=args.trust_remote_code,
+ )
+ raw_datasets["train"] = load_dataset(
+ args.dataset_name,
+ args.dataset_config_name,
+ split=f"train[{args.validation_split_percentage}%:]",
+ trust_remote_code=args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ dataset_args = {}
+ if args.train_file is not None:
+ data_files["train"] = args.train_file
+ extension = args.train_file.split(".")[-1]
+ if args.validation_file is not None:
+ data_files["validation"] = args.validation_file
+ extension = args.validation_file.split(".")[-1]
+ if extension == "txt":
+ extension = "text"
+ dataset_args["keep_linebreaks"] = not args.no_keep_linebreaks
+ raw_datasets = load_dataset(extension, data_files=data_files, **dataset_args)
+ # If no validation data is there, validation_split_percentage will be used to divide the dataset.
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[:{args.validation_split_percentage}%]",
+ **dataset_args,
+ )
+ raw_datasets["train"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[{args.validation_split_percentage}%:]",
+ **dataset_args,
+ )
+
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+ #
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ if args.config_name:
+ config = AutoConfig.from_pretrained(
+ args.config_name,
+ trust_remote_code=args.trust_remote_code,
+ )
+ elif args.model_name_or_path:
+ config = AutoConfig.from_pretrained(
+ args.model_name_or_path,
+ trust_remote_code=args.trust_remote_code,
+ )
+ else:
+ config = CONFIG_MAPPING[args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ if args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.tokenizer_name, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
+ )
+ elif args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.model_name_or_path, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
+ )
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if args.model_name_or_path:
+ model = AutoModelForCausalLM.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ low_cpu_mem_usage=args.low_cpu_mem_usage,
+ trust_remote_code=args.trust_remote_code,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = AutoModelForCausalLM.from_config(config, trust_remote_code=args.trust_remote_code)
+
+ # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
+ # on a small vocab and want a smaller embedding size, remove this test.
+ embedding_size = model.get_input_embeddings().weight.shape[0]
+ if len(tokenizer) > embedding_size:
+ model.resize_token_embeddings(len(tokenizer))
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ column_names = raw_datasets["train"].column_names
+ text_column_name = "text" if "text" in column_names else column_names[0]
+
+ def tokenize_function(examples):
+ return tokenizer(examples[text_column_name])
+
+ with accelerator.main_process_first():
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Running tokenizer on dataset",
+ )
+
+ if args.block_size is None:
+ block_size = tokenizer.model_max_length
+ if block_size > config.max_position_embeddings:
+ logger.warning(
+ f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
+ f"Using block_size={min(1024, config.max_position_embeddings)} instead. You can change that default value by passing --block_size xxx."
+ )
+ block_size = min(1024, config.max_position_embeddings)
+ else:
+ if args.block_size > tokenizer.model_max_length:
+ logger.warning(
+ f"The block_size passed ({args.block_size}) is larger than the maximum length for the model "
+ f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
+ )
+ block_size = min(args.block_size, tokenizer.model_max_length)
+
+ # Main data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
+ def group_texts(examples):
+ # Concatenate all texts.
+ concatenated_examples = {k: list(chain(*examples[k])) for k in examples.keys()}
+ total_length = len(concatenated_examples[list(examples.keys())[0]])
+ # We drop the small remainder, and if the total_length < block_size we exclude this batch and return an empty dict.
+ # We could add padding if the model supported it instead of this drop, you can customize this part to your needs.
+ total_length = (total_length // block_size) * block_size
+ # Split by chunks of max_len.
+ result = {
+ k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
+ for k, t in concatenated_examples.items()
+ }
+ result["labels"] = result["input_ids"].copy()
+ return result
+
+ # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
+ # for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
+ # to preprocess.
+ #
+ # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
+ # https://huggingface.co/docs/datasets/process#map
+
+ with accelerator.main_process_first():
+ lm_datasets = tokenized_datasets.map(
+ group_texts,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ load_from_cache_file=not args.overwrite_cache,
+ desc=f"Grouping texts in chunks of {block_size}",
+ )
+
+ train_dataset = lm_datasets["train"]
+ eval_dataset = lm_datasets["validation"]
+
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ # DataLoaders creation:
+ train_dataloader = DataLoader(
+ train_dataset, shuffle=True, collate_fn=default_data_collator, batch_size=args.per_device_train_batch_size
+ )
+ eval_dataloader = DataLoader(
+ eval_dataset, collate_fn=default_data_collator, batch_size=args.per_device_eval_batch_size
+ )
+
+ # Optimizer
+ # Split weights in two groups, one with weight decay and the other not.
+ no_decay = ["bias", "layer_norm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
+ num_training_steps=args.max_train_steps
+ if overrode_max_train_steps
+ else args.max_train_steps * accelerator.num_processes,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # On TPU, the tie weights in our model have been disconnected, so we need to restore the ties.
+ if accelerator.distributed_type == DistributedType.TPU:
+ model.tie_weights()
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("clm_no_trainer", experiment_config)
+
+ # Train!
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ checkpoint_path = args.resume_from_checkpoint
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ checkpoint_path = path
+ path = os.path.basename(checkpoint_path)
+
+ accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
+ accelerator.load_state(checkpoint_path)
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ completed_steps = resume_step // args.gradient_accumulation_steps
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We skip the first `n` batches in the dataloader when resuming from a checkpoint
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ with accelerator.accumulate(model):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # Checks if the accelerator has performed an optimization step behind the scenes
+ if accelerator.sync_gradients:
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+ if completed_steps >= args.max_train_steps:
+ break
+
+ model.eval()
+ losses = []
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+
+ loss = outputs.loss
+ losses.append(accelerator.gather_for_metrics(loss.repeat(args.per_device_eval_batch_size)))
+
+ losses = torch.cat(losses)
+ try:
+ eval_loss = torch.mean(losses)
+ perplexity = math.exp(eval_loss)
+ except OverflowError:
+ perplexity = float("inf")
+
+ logger.info(f"epoch {epoch}: perplexity: {perplexity} eval_loss: {eval_loss}")
+
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "perplexity": perplexity,
+ "eval_loss": eval_loss,
+ "train_loss": total_loss.item() / len(train_dataloader),
+ "epoch": epoch,
+ "step": completed_steps,
+ },
+ step=completed_steps,
+ )
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if args.checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.with_tracking:
+ accelerator.end_training()
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ if args.push_to_hub:
+ api.upload_folder(
+ commit_message="End of training",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+ with open(os.path.join(args.output_dir, "all_results.json"), "w") as f:
+ json.dump({"perplexity": perplexity}, f)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_fim.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_fim.py
new file mode 100644
index 0000000000000000000000000000000000000000..e94690eaa7fcd3ac64559247b831e546f84befc0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_fim.py
@@ -0,0 +1,864 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for causal language modeling using
+Fill-in-the middle (FIM) objective on a text file or a dataset.
+
+Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
+https://huggingface.co/models?filter=text-generation
+"""
+# You should adapt this script on your own causal language modeling task. Pointers for this are left as comments.
+
+import logging
+import math
+import os
+import sys
+from dataclasses import dataclass, field
+from itertools import chain
+from typing import Optional
+
+import datasets
+import evaluate
+import numpy as np
+import torch
+from datasets import load_dataset
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ MODEL_FOR_CAUSAL_LM_MAPPING,
+ AutoConfig,
+ AutoModelForCausalLM,
+ AutoTokenizer,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ default_data_collator,
+ is_torch_tpu_available,
+ set_seed,
+)
+from transformers.integrations import is_deepspeed_zero3_enabled
+from transformers.testing_utils import CaptureLogger
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
+
+logger = logging.getLogger(__name__)
+
+
+MODEL_CONFIG_CLASSES = list(MODEL_FOR_CAUSAL_LM_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ model_name_or_path: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
+ )
+ },
+ )
+ model_type: Optional[str] = field(
+ default=None,
+ metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
+ )
+ config_overrides: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Override some existing default config settings when a model is trained from scratch. Example: "
+ "n_embd=10,resid_pdrop=0.2,scale_attn_weights=false,summary_type=cls_index"
+ )
+ },
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ torch_dtype: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Override the default `torch.dtype` and load the model under this dtype. If `auto` is passed, the "
+ "dtype will be automatically derived from the model's weights."
+ ),
+ "choices": ["auto", "bfloat16", "float16", "float32"],
+ },
+ )
+ low_cpu_mem_usage: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "It is an option to create the model as an empty shell, then only materialize its parameters when the pretrained weights are loaded. "
+ "set True will benefit LLM loading time and RAM consumption."
+ )
+ },
+ )
+ pad_to_multiple_of: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to pad the embedding layer to a multiple depending on the device. ",
+ "For NVIDIA GPUs, this will be a multiple of 8, for TPUs a multiple of 128.",
+ )
+ },
+ )
+ attn_implementation: Optional[str] = field(
+ default="sdpa", metadata={"help": ("The attention implementation to use. ")}
+ )
+
+ def __post_init__(self):
+ if self.config_overrides is not None and (self.config_name is not None or self.model_name_or_path is not None):
+ raise ValueError(
+ "--config_overrides can't be used in combination with --config_name or --model_name_or_path"
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ streaming: bool = field(default=False, metadata={"help": "Enable streaming mode"})
+ block_size: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Optional input sequence length after tokenization. "
+ "The training dataset will be truncated in block of this size for training. "
+ "Default to the model max input length for single sentence inputs (take into account special tokens)."
+ )
+ },
+ )
+ fim_rate: Optional[float] = field(
+ default=0.5,
+ metadata={
+ "help": (
+ "Optional probability with which the FIM transformation is applied to the example. "
+ "Default is 0.5. A rate of 1.0 means every example will undergo FIM transformation, "
+ "while a rate of 0.0 means no example will."
+ )
+ },
+ )
+ fim_spm_rate: Optional[float] = field(
+ default=0.5,
+ metadata={
+ "help": (
+ "Within the examples undergoing FIM transformation, this rate determines the probability "
+ "of applying the Sentence Permutation Mode (SPM). "
+ "Default is 0.5. A rate of 1.0 means all FIM transformations will use SPM, "
+ "while a rate of 0.0 means none will."
+ )
+ },
+ )
+ truncate_or_pad: Optional[bool] = field(
+ default=True,
+ metadata={
+ "help": (
+ "Indicates whether the transformed example should be truncated or padded to maintain "
+ "the same length as the original example. "
+ "Default is True. If False, the function will not truncate or pad the examples."
+ )
+ },
+ )
+ fim_prefix_token: Optional[str] = field(
+ default="",
+ metadata={"help": ("Fill-in-Middle Prefix token. Defaults to ''.")},
+ )
+ fim_middle_token: Optional[str] = field(
+ default="",
+ metadata={"help": ("Fill-in-Middle Middle token. Defaults to ''.")},
+ )
+ fim_suffix_token: Optional[str] = field(
+ default="",
+ metadata={"help": ("Fill-in-Middle Suffix token. Defaults to ''.")},
+ )
+ pad_token: Optional[str] = field(
+ default="",
+ metadata={
+ "help": (
+ "Fill-in-Middle Pad token. Used only when 'truncate_or_pad' is set to True. "
+ "Defaults to ''."
+ )
+ },
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ validation_split_percentage: Optional[int] = field(
+ default=5,
+ metadata={
+ "help": "The percentage of the train set used as validation set in case there's no validation split"
+ },
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ keep_linebreaks: bool = field(
+ default=True, metadata={"help": "Whether to keep line breaks when using TXT files or not."}
+ )
+
+ def __post_init__(self):
+ if self.streaming:
+ require_version("datasets>=2.0.0", "The streaming feature requires `datasets>=2.0.0`")
+
+ if self.dataset_name is None and self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, a json or a txt file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, a json or a txt file."
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_fim", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ datasets.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Set a numpy random state for FIM transformations
+ np_rng = np.random.RandomState(seed=training_args.seed)
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ streaming=data_args.streaming,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ streaming=data_args.streaming,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ raw_datasets["train"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ streaming=data_args.streaming,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ dataset_args = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = (
+ data_args.train_file.split(".")[-1]
+ if data_args.train_file is not None
+ else data_args.validation_file.split(".")[-1]
+ )
+ if extension == "txt":
+ extension = "text"
+ dataset_args["keep_linebreaks"] = data_args.keep_linebreaks
+ raw_datasets = load_dataset(
+ extension,
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ **dataset_args,
+ )
+ # If no validation data is there, validation_split_percentage will be used to divide the dataset.
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ **dataset_args,
+ )
+ raw_datasets["train"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ **dataset_args,
+ )
+
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.html.
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+
+ config_kwargs = {
+ "cache_dir": model_args.cache_dir,
+ "revision": model_args.model_revision,
+ "token": model_args.token,
+ "trust_remote_code": model_args.trust_remote_code,
+ }
+ if model_args.config_name:
+ config = AutoConfig.from_pretrained(model_args.config_name, **config_kwargs)
+ elif model_args.model_name_or_path:
+ config = AutoConfig.from_pretrained(model_args.model_name_or_path, **config_kwargs)
+ else:
+ config = CONFIG_MAPPING[model_args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+ if model_args.config_overrides is not None:
+ logger.info(f"Overriding config: {model_args.config_overrides}")
+ config.update_from_string(model_args.config_overrides)
+ logger.info(f"New config: {config}")
+
+ tokenizer_kwargs = {
+ "cache_dir": model_args.cache_dir,
+ "use_fast": model_args.use_fast_tokenizer,
+ "revision": model_args.model_revision,
+ "token": model_args.token,
+ "trust_remote_code": model_args.trust_remote_code,
+ }
+ if model_args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(model_args.tokenizer_name, **tokenizer_kwargs)
+ elif model_args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(model_args.model_name_or_path, **tokenizer_kwargs)
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if model_args.model_name_or_path:
+ torch_dtype = (
+ model_args.torch_dtype
+ if model_args.torch_dtype in ["auto", None]
+ else getattr(torch, model_args.torch_dtype)
+ )
+ model = AutoModelForCausalLM.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ torch_dtype=torch_dtype,
+ low_cpu_mem_usage=model_args.low_cpu_mem_usage,
+ attn_implementation=model_args.attn_implementation,
+ )
+
+ else:
+ model = AutoModelForCausalLM.from_config(
+ config,
+ trust_remote_code=model_args.trust_remote_code,
+ attn_implementation=model_args.attn_implementation,
+ )
+ n_params = sum({p.data_ptr(): p.numel() for p in model.parameters()}.values())
+ logger.info(f"Training new model from scratch - Total size={n_params/2**20:.2f}M params")
+
+ # Add the new FIM tokens to the tokenizer and resize model's vocab embeddings
+ special_tokens = [data_args.fim_prefix_token, data_args.fim_middle_token, data_args.fim_suffix_token]
+ if data_args.truncate_or_pad:
+ special_tokens.append(data_args.pad_token)
+
+ # Get the factor by which the embedding layer should be padded based on the device
+ pad_factor = 1
+ if torch.cuda.is_availble():
+ pad_factor = 8
+
+ elif is_torch_tpu_available():
+ pad_factor = 128
+
+ # Add the new tokens to the tokenizer
+ tokenizer.add_tokens(special_tokens)
+ original_embeddings = model.get_input_embeddings()
+
+ if is_deepspeed_zero3_enabled():
+ import deepspeed
+
+ with deepspeed.zero.GatheredParameters(original_embeddings.weight, modifier_rank=0):
+ # Get the pre-expansion embeddings of the model and resize the embedding layer
+ model.resize_token_embeddings(len(tokenizer), pad_to_multiple_of=pad_factor)
+ embeddings = model.get_input_embeddings()
+
+ # Sample the embeddings for the new tokens from a multivariate normal distribution
+ # We do this so that the new embeddings are close to the original embeddings and not necessarily zero
+ # More on this: https://nlp.stanford.edu/~johnhew/vocab-expansion.html
+ mean = original_embeddings.mean(dim=0)
+ n = original_embeddings.size()[0]
+ sigma = ((original_embeddings - mean).T @ (original_embeddings - mean)) / n
+ dist = torch.distributions.multivariate_normal.MultivariateNormal(
+ mean,
+ covariance_matrix=1e-5 * sigma,
+ )
+ new_token_embeddings = torch.stack(
+ tuple((dist.sample() for _ in range(len(special_tokens)))),
+ dim=0,
+ )
+ else:
+ original_embeddings = model.get_input_embeddings()
+ # Get the pre-expansion embeddings of the model and resize the embedding layer
+ model.resize_token_embeddings(len(tokenizer), pad_to_multiple_of=pad_factor)
+ embeddings = model.get_input_embeddings()
+
+ # Sample the embeddings for the new tokens from a multivariate normal distribution
+ # We do this so that the new embeddings are close to the original embeddings and not necessarily zero
+ # More on this: https://nlp.stanford.edu/~johnhew/vocab-expansion.html
+ mean = original_embeddings.mean(dim=0)
+ n = original_embeddings.size()[0]
+ sigma = ((original_embeddings - mean).T @ (original_embeddings - mean)) / n
+ dist = torch.distributions.multivariate_normal.MultivariateNormal(
+ mean,
+ covariance_matrix=1e-5 * sigma,
+ )
+ new_token_embeddings = torch.stack(
+ tuple((dist.sample() for _ in range(len(special_tokens)))),
+ dim=0,
+ )
+
+ if is_deepspeed_zero3_enabled():
+ import deepspeed
+
+ with deepspeed.zero.GatheredParameters(embeddings.weight, modifier_rank=0):
+ # Set the new tokens' embeddings to the newly sampled embeddings
+ embeddings.weight.data[-len(special_tokens) :] = new_token_embeddings
+ else:
+ # Set the new tokens' embeddings to the newly sampled embeddings
+ embeddings.weight.data[-len(special_tokens) :] = new_token_embeddings
+
+ # Update the model's embeddings with the new embeddings
+ model.set_input_embeddings(embeddings)
+
+ logger.info("Added special tokens to the tokenizer and resized model's embedding layer")
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ if training_args.do_train:
+ column_names = list(raw_datasets["train"].features)
+ else:
+ column_names = list(raw_datasets["validation"].features)
+ text_column_name = "text" if "text" in column_names else column_names[0]
+
+ # since this will be pickled to avoid _LazyModule error in Hasher force logger loading before tokenize_function
+ tok_logger = transformers.utils.logging.get_logger("transformers.tokenization_utils_base")
+
+ def tokenize_function(examples):
+ with CaptureLogger(tok_logger) as cl:
+ output = tokenizer(examples[text_column_name])
+ # clm-fim input could be much much longer than block_size
+ if "Token indices sequence length is longer than the" in cl.out:
+ tok_logger.warning(
+ "^^^^^^^^^^^^^^^^ Please ignore the warning above - this long input will be chunked into smaller bits"
+ " before being passed to the model."
+ )
+ return output
+
+ with training_args.main_process_first(desc="dataset map tokenization"):
+ if not data_args.streaming:
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on dataset",
+ )
+ else:
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=column_names,
+ )
+
+ if data_args.block_size is None:
+ block_size = tokenizer.model_max_length
+ if block_size > config.max_position_embeddings:
+ logger.warning(
+ f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
+ f"Using block_size={min(1024, config.max_position_embeddings)} instead. You can change that default value by passing --block_size xxx."
+ )
+ block_size = min(1024, config.max_position_embeddings)
+ else:
+ if data_args.block_size > tokenizer.model_max_length:
+ logger.warning(
+ f"The block_size passed ({data_args.block_size}) is larger than the maximum length for the model "
+ f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
+ )
+ block_size = min(data_args.block_size, tokenizer.model_max_length)
+
+ # Data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
+ def group_texts(examples):
+ # Concatenate all texts.
+ concatenated_examples = {k: list(chain(*examples[k])) for k in examples.keys()}
+ total_length = len(concatenated_examples[list(examples.keys())[0]])
+ # We drop the small remainder, and if the total_length < block_size we exclude this batch and return an empty dict.
+ # We could add padding if the model supported it instead of this drop, you can customize this part to your needs.
+ total_length = (total_length // block_size) * block_size
+ # Split by chunks of max_len.
+ result = {
+ k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
+ for k, t in concatenated_examples.items()
+ }
+ result["labels"] = result["input_ids"].copy()
+ return result
+
+ # Get the FIM-specific token ids
+ prefix_tok_id = tokenizer.convert_tokens_to_ids(data_args.fim_prefix_token)
+ middle_tok_id = tokenizer.convert_tokens_to_ids(data_args.fim_middle_token)
+ suffix_tok_id = tokenizer.convert_tokens_to_ids(data_args.fim_suffix_token)
+ pad_tok_id = None
+
+ # If truncate_or_pad is on, also get pad token id
+ if data_args.truncate_or_pad:
+ pad_tok_id = tokenizer.convert_tokens_to_ids(data_args.pad_token)
+
+ # The two functions below perform the FIM transformation on the data (either PSM or SPM or PSM+SPM)
+ # Don't call fim_transform directly in .map()
+ # Adapted from https://github.com/loubnabnl/santacoder-finetuning/blob/main/fim.py#L22C13-L83
+ def fim_transform(example):
+ """
+ This function performs FIM transformation on a single example (list of tokens)
+ """
+ if np_rng.binomial(1, data_args.fim_rate):
+ boundaries = sorted(np_rng.randint(low=0, high=len(example) + 1, size=2))
+
+ prefix = example[: boundaries[0]]
+ middle = example[boundaries[0] : boundaries[1]]
+ suffix = example[boundaries[1] :]
+
+ if data_args.truncate_or_pad:
+ total_length = len(prefix) + len(middle) + len(suffix) + 3
+ diff = total_length - len(example)
+ if diff > 0:
+ suffix = suffix[: max(0, len(suffix) - diff)]
+ elif diff < 0:
+ suffix.extend([pad_tok_id] * (-diff))
+
+ if np_rng.binomial(1, data_args.fim_spm_rate):
+ # Apply Suffix-Prefix-Middle (SPM) transformation
+ transformed_example = [prefix_tok_id, suffix_tok_id] + suffix + [middle_tok_id] + prefix + middle
+ else:
+ # Apply Prefix-Suffix-Middle (PSM) transformation
+ transformed_example = [prefix_tok_id] + prefix + [suffix_tok_id] + suffix + [middle_tok_id] + middle
+ else:
+ transformed_example = example
+
+ return transformed_example
+
+ # Below function is the one you are supposed to call in the .map() function
+ def apply_fim(examples):
+ """
+ Apply FIM transformation to a batch of examples
+ """
+ fim_transform_ids = [fim_transform(ids) for ids in examples["input_ids"]]
+ examples["input_ids"] = fim_transform_ids
+ examples["labels"] = fim_transform_ids
+ # If your application requires custom attention mask, please adjust this function's below line.
+ # Since FIM transformation increases the number of tokens in input_ids and labels
+ # but leaves the number of tokens unchanged in attention_masks which would cause problems
+ examples["attention_mask"] = [[1] * len(mask) for mask in examples["input_ids"]]
+ return examples
+
+ # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
+ # for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
+ # to preprocess.
+ #
+ # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
+ # https://huggingface.co/docs/datasets/process#map
+
+ # FIM transformations are only supposed to be applied before group_texts processing otherwise some sentences will
+ # have 3-4 more tokens than others due to probabilistic addition of FIM-specific tokens which will raise errors
+ with training_args.main_process_first(desc="processing texts together"):
+ if not data_args.streaming:
+ fim_datasets = tokenized_datasets.map(
+ apply_fim,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Performing FIM transformation",
+ )
+ lm_datasets = fim_datasets.map(
+ group_texts,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc=f"Grouping texts in chunks of {block_size}",
+ )
+ else:
+ fim_datasets = tokenized_datasets.map(
+ apply_fim,
+ batched=True,
+ )
+ lm_datasets = fim_datasets.map(
+ group_texts,
+ batched=True,
+ )
+
+ if training_args.do_train:
+ if "train" not in tokenized_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = lm_datasets["train"]
+ if data_args.max_train_samples is not None:
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+
+ if training_args.do_eval:
+ if "validation" not in tokenized_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_dataset = lm_datasets["validation"]
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+
+ def preprocess_logits_for_metrics(logits, labels):
+ if isinstance(logits, tuple):
+ # Depending on the model and config, logits may contain extra tensors,
+ # like past_key_values, but logits always come first
+ logits = logits[0]
+ return logits.argmax(dim=-1)
+
+ metric = evaluate.load("accuracy")
+
+ def compute_metrics(eval_preds):
+ preds, labels = eval_preds
+ # preds have the same shape as the labels, after the argmax(-1) has been calculated
+ # by preprocess_logits_for_metrics but we need to shift the labels
+ labels = labels[:, 1:].reshape(-1)
+ preds = preds[:, :-1].reshape(-1)
+ return metric.compute(predictions=preds, references=labels)
+
+ # Initialize our Trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset if training_args.do_train else None,
+ eval_dataset=eval_dataset if training_args.do_eval else None,
+ processing_class=tokenizer,
+ # Data collator will default to DataCollatorWithPadding, so we change it.
+ data_collator=default_data_collator,
+ compute_metrics=compute_metrics if training_args.do_eval and not is_torch_tpu_available() else None,
+ preprocess_logits_for_metrics=(
+ preprocess_logits_for_metrics if training_args.do_eval and not is_torch_tpu_available() else None
+ ),
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model() # Saves the tokenizer too for easy upload
+
+ metrics = train_result.metrics
+
+ max_train_samples = (
+ data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
+ )
+ metrics["train_samples"] = min(max_train_samples, len(train_dataset))
+
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+
+ metrics = trainer.evaluate()
+
+ max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
+ metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
+ try:
+ perplexity = math.exp(metrics["eval_loss"])
+ except OverflowError:
+ perplexity = float("inf")
+ metrics["perplexity"] = perplexity
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "text-generation"}
+ if data_args.dataset_name is not None:
+ kwargs["dataset_tags"] = data_args.dataset_name
+ if data_args.dataset_config_name is not None:
+ kwargs["dataset_args"] = data_args.dataset_config_name
+ kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
+ else:
+ kwargs["dataset"] = data_args.dataset_name
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_fim_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_fim_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..64e340a62a763901040c4a442100581dad17ac7e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_fim_no_trainer.py
@@ -0,0 +1,916 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for causal language modeling using
+Fill-in-the middle (FIM) objective on a text file or a dataset without using HuggingFace Trainer.
+
+Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
+https://huggingface.co/models?filter=text-generation
+"""
+# You can also adapt this script on your own fim causal language modeling task. Pointers for this are left as comments.
+
+import argparse
+import json
+import logging
+import math
+import os
+import random
+from itertools import chain
+from pathlib import Path
+
+import datasets
+import numpy as np
+import torch
+from accelerate import Accelerator, DistributedType
+from accelerate.logging import get_logger
+from accelerate.utils import set_seed
+from datasets import load_dataset
+from huggingface_hub import Repository, create_repo
+from torch.utils.data import DataLoader
+from tqdm.auto import tqdm
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ MODEL_MAPPING,
+ AutoConfig,
+ AutoModelForCausalLM,
+ AutoTokenizer,
+ SchedulerType,
+ default_data_collator,
+ get_scheduler,
+ is_torch_tpu_available,
+)
+from transformers.integrations import is_deepspeed_zero3_enabled
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+logger = get_logger(__name__)
+
+require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
+
+MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(
+ description="Finetune a transformers model on a causal language modeling task using fill-in-the middle objective"
+ )
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ default=None,
+ help="The name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--dataset_config_name",
+ type=str,
+ default=None,
+ help="The configuration name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--train_file", type=str, default=None, help="A csv, txt or a json file containing the training data."
+ )
+ parser.add_argument(
+ "--validation_file", type=str, default=None, help="A csv, txt or a json file containing the validation data."
+ )
+ parser.add_argument(
+ "--validation_split_percentage",
+ default=5,
+ help="The percentage of the train set used as validation set in case there's no validation split",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=False,
+ )
+ parser.add_argument(
+ "--config_name",
+ type=str,
+ default=None,
+ help="Pretrained config name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ type=str,
+ default=None,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--use_slow_tokenizer",
+ action="store_true",
+ help="If passed, will use a slow tokenizer (not backed by the 🤗 Tokenizers library).",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=42, help="A seed for reproducible training.")
+ parser.add_argument(
+ "--model_type",
+ type=str,
+ default=None,
+ help="Model type to use if training from scratch.",
+ choices=MODEL_TYPES,
+ )
+ parser.add_argument(
+ "--block_size",
+ type=int,
+ default=None,
+ help=(
+ "Optional input sequence length after tokenization. The training dataset will be truncated in block of"
+ " this size for training. Default to the model max input length for single sentence inputs (take into"
+ " account special tokens)."
+ ),
+ )
+ parser.add_argument(
+ "--fim_rate",
+ type=float,
+ default=0.5,
+ help=(
+ " Optional probability with which the FIM transformation is applied to the example."
+ " Default is 0.5. A rate of 1.0 means every example will undergo FIM transformation,"
+ " while a rate of 0.0 means no example will."
+ ),
+ )
+ parser.add_argument(
+ "--fim_spm_rate",
+ type=float,
+ default=0.5,
+ help=(
+ "Within the examples undergoing FIM transformation, this rate determines the probability"
+ " of applying the Sentence Permutation Mode (SPM)."
+ " Default is 0.5. A rate of 1.0 means all FIM transformations will use SPM,"
+ " while a rate of 0.0 means none will."
+ ),
+ )
+ parser.add_argument(
+ "--truncate_or_pad",
+ type=bool,
+ default=True,
+ help=(
+ "Indicates whether the transformed example should be truncated or padded to maintain"
+ " the same length as the original example."
+ " Default is True. If False, the function will not truncate or pad the examples."
+ ),
+ )
+ parser.add_argument(
+ "--fim_prefix_token",
+ type=str,
+ default="",
+ help="Fill-in-Middle Prefix token. Defaults to ''.",
+ )
+ parser.add_argument(
+ "--fim_middle_token",
+ type=str,
+ default="",
+ help="Fill-in-Middle Middle token. Defaults to ''.",
+ )
+ parser.add_argument(
+ "--fim_suffix_token",
+ type=str,
+ default="",
+ help="Fill-in-Middle Middle token. Defaults to ''.",
+ )
+ parser.add_argument(
+ "--fim_pad_token",
+ type=str,
+ default="",
+ help=(
+ "Fill-in-Middle Pad token. Used only when 'truncate_or_pad' is set to True." " Defaults to ''."
+ ),
+ )
+ parser.add_argument(
+ "--preprocessing_num_workers",
+ type=int,
+ default=None,
+ help="The number of processes to use for the preprocessing.",
+ )
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+ parser.add_argument(
+ "--no_keep_linebreaks", action="store_true", help="Do not keep line breaks when using TXT files."
+ )
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--trust_remote_code",
+ action="store_true",
+ help=(
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ parser.add_argument(
+ "--low_cpu_mem_usage",
+ action="store_true",
+ help=(
+ "It is an option to create the model as an empty shell, then only materialize its parameters when the pretrained weights are loaded. "
+ "If passed, LLM loading time and RAM consumption will be benefited."
+ ),
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+ if args.dataset_name is None and args.train_file is None and args.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if args.train_file is not None:
+ extension = args.train_file.split(".")[-1]
+ if extension not in ["csv", "json", "txt"]:
+ raise ValueError("`train_file` should be a csv, json or txt file.")
+ if args.validation_file is not None:
+ extension = args.validation_file.split(".")[-1]
+ if extension not in ["csv", "json", "txt"]:
+ raise ValueError("`validation_file` should be a csv, json or txt file.")
+
+ if args.push_to_hub:
+ if args.output_dir is None:
+ raise ValueError("Need an `output_dir` to create a repo when `--push_to_hub` is passed.")
+
+ return args
+
+
+def main():
+ args = parse_args()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_fim_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+ accelerator_log_kwargs = {}
+
+ if args.with_tracking:
+ accelerator_log_kwargs["log_with"] = args.report_to
+ accelerator_log_kwargs["project_dir"] = args.output_dir
+
+ accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+ # Set a numpy random state for FIM transformations
+ np_rng = np.random.RandomState(seed=args.seed)
+ else:
+ # Still set a random state for FIM transformations
+ np_rng = np.random.RandomState(seed=42)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ repo_id = create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+ # Clone repo locally
+ repo = Repository(args.output_dir, clone_from=repo_id, token=args.hub_token)
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
+ )
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ args.dataset_name,
+ args.dataset_config_name,
+ split=f"train[:{args.validation_split_percentage}%]",
+ trust_remote_code=args.trust_remote_code,
+ )
+ raw_datasets["train"] = load_dataset(
+ args.dataset_name,
+ args.dataset_config_name,
+ split=f"train[{args.validation_split_percentage}%:]",
+ trust_remote_code=args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ dataset_args = {}
+ if args.train_file is not None:
+ data_files["train"] = args.train_file
+ if args.validation_file is not None:
+ data_files["validation"] = args.validation_file
+ extension = args.train_file.split(".")[-1]
+ if extension == "txt":
+ extension = "text"
+ dataset_args["keep_linebreaks"] = not args.no_keep_linebreaks
+ raw_datasets = load_dataset(extension, data_files=data_files, **dataset_args)
+ # If no validation data is there, validation_split_percentage will be used to divide the dataset.
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[:{args.validation_split_percentage}%]",
+ **dataset_args,
+ )
+ raw_datasets["train"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[{args.validation_split_percentage}%:]",
+ **dataset_args,
+ )
+
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.html.
+
+ # Load pretrained model and tokenizer
+ #
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ if args.config_name:
+ config = AutoConfig.from_pretrained(
+ args.config_name,
+ trust_remote_code=args.trust_remote_code,
+ )
+ elif args.model_name_or_path:
+ config = AutoConfig.from_pretrained(
+ args.model_name_or_path,
+ trust_remote_code=args.trust_remote_code,
+ )
+ else:
+ config = CONFIG_MAPPING[args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ if args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.tokenizer_name, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
+ )
+ elif args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.model_name_or_path, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
+ )
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if args.model_name_or_path:
+ model = AutoModelForCausalLM.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ low_cpu_mem_usage=args.low_cpu_mem_usage,
+ trust_remote_code=args.trust_remote_code,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = AutoModelForCausalLM.from_config(config, trust_remote_code=args.trust_remote_code)
+
+ # Add the new FIM tokens to the tokenizer and resize model's vocab embeddings
+ special_tokens = [args.fim_prefix_token, args.fim_middle_token, args.fim_suffix_token]
+ if args.truncate_or_pad:
+ special_tokens.append(args.fim_pad_token)
+
+ # Get the factor by which the embedding layer should be padded based on the device
+ pad_factor = 1
+ if torch.cuda.is_availble():
+ pad_factor = 8
+
+ elif is_torch_tpu_available():
+ pad_factor = 128
+
+ # Add the new tokens to the tokenizer
+ tokenizer.add_tokens(special_tokens)
+ original_embeddings = model.get_input_embeddings()
+
+ if is_deepspeed_zero3_enabled():
+ import deepspeed
+
+ with deepspeed.zero.GatheredParameters(original_embeddings.weight, modifier_rank=0):
+ # Get the pre-expansion embeddings of the model and resize the embedding layer
+ model.resize_token_embeddings(len(tokenizer), pad_to_multiple_of=pad_factor)
+ embeddings = model.get_input_embeddings()
+
+ # Sample the embeddings for the new tokens from a multivariate normal distribution
+ # We do this so that the new embeddings are close to the original embeddings and not necessarily zero
+ # More on this: https://nlp.stanford.edu/~johnhew/vocab-expansion.html
+ mean = original_embeddings.mean(dim=0)
+ n = original_embeddings.size()[0]
+ sigma = ((original_embeddings - mean).T @ (original_embeddings - mean)) / n
+ dist = torch.distributions.multivariate_normal.MultivariateNormal(
+ mean,
+ covariance_matrix=1e-5 * sigma,
+ )
+ new_token_embeddings = torch.stack(
+ tuple((dist.sample() for _ in range(len(special_tokens)))),
+ dim=0,
+ )
+ else:
+ original_embeddings = model.get_input_embeddings()
+ # Get the pre-expansion embeddings of the model and resize the embedding layer
+ model.resize_token_embeddings(len(tokenizer), pad_to_multiple_of=pad_factor)
+ embeddings = model.get_input_embeddings()
+
+ # Sample the embeddings for the new tokens from a multivariate normal distribution
+ # We do this so that the new embeddings are close to the original embeddings and not necessarily zero
+ # More on this: https://nlp.stanford.edu/~johnhew/vocab-expansion.html
+ mean = original_embeddings.mean(dim=0)
+ n = original_embeddings.size()[0]
+ sigma = ((original_embeddings - mean).T @ (original_embeddings - mean)) / n
+ dist = torch.distributions.multivariate_normal.MultivariateNormal(
+ mean,
+ covariance_matrix=1e-5 * sigma,
+ )
+ new_token_embeddings = torch.stack(
+ tuple((dist.sample() for _ in range(len(special_tokens)))),
+ dim=0,
+ )
+
+ if is_deepspeed_zero3_enabled():
+ import deepspeed
+
+ with deepspeed.zero.GatheredParameters(embeddings.weight, modifier_rank=0):
+ # Set the new tokens' embeddings to the newly sampled embeddings
+ embeddings.weight.data[-len(special_tokens) :] = new_token_embeddings
+ else:
+ # Set the new tokens' embeddings to the newly sampled embeddings
+ embeddings.weight.data[-len(special_tokens) :] = new_token_embeddings
+
+ # Update the model's embeddings with the new embeddings
+ model.set_input_embeddings(embeddings)
+
+ logger.info("Added special tokens to the tokenizer and resized model's embedding layer")
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ column_names = raw_datasets["train"].column_names
+ text_column_name = "text" if "text" in column_names else column_names[0]
+
+ def tokenize_function(examples):
+ return tokenizer(examples[text_column_name])
+
+ with accelerator.main_process_first():
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Running tokenizer on dataset",
+ )
+
+ if args.block_size is None:
+ block_size = tokenizer.model_max_length
+ if block_size > config.max_position_embeddings:
+ logger.warning(
+ f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
+ f"Using block_size={min(1024, config.max_position_embeddings)} instead. You can change that default value by passing --block_size xxx."
+ )
+ block_size = min(1024, config.max_position_embeddings)
+ else:
+ if args.block_size > tokenizer.model_max_length:
+ logger.warning(
+ f"The block_size passed ({args.block_size}) is larger than the maximum length for the model "
+ f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
+ )
+ block_size = min(args.block_size, tokenizer.model_max_length)
+
+ # Main data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
+ def group_texts(examples):
+ # Concatenate all texts.
+ concatenated_examples = {k: list(chain(*examples[k])) for k in examples.keys()}
+ total_length = len(concatenated_examples[list(examples.keys())[0]])
+ # We drop the small remainder, and if the total_length < block_size we exclude this batch and return an empty dict.
+ # We could add padding if the model supported it instead of this drop, you can customize this part to your needs.
+ total_length = (total_length // block_size) * block_size
+ # Split by chunks of max_len.
+ result = {
+ k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
+ for k, t in concatenated_examples.items()
+ }
+ result["labels"] = result["input_ids"].copy()
+ return result
+
+ # Get the FIM-specific token ids
+ prefix_tok_id = tokenizer.convert_tokens_to_ids(args.fim_prefix_token)
+ middle_tok_id = tokenizer.convert_tokens_to_ids(args.fim_middle_token)
+ suffix_tok_id = tokenizer.convert_tokens_to_ids(args.fim_suffix_token)
+ pad_tok_id = None
+
+ # If truncate_or_pad is on, also get pad token id
+ if args.truncate_or_pad:
+ pad_tok_id = tokenizer.convert_tokens_to_ids(args.fim_pad_token)
+
+ # The two functions below perform the FIM transformation on the data (either PSM or SPM or PSM+SPM)
+ # Don't call fim_transform directly in .map()
+ # Adapted from https://github.com/loubnabnl/santacoder-finetuning/blob/main/fim.py#L22C13-L83
+ def fim_transform(example):
+ """
+ This function performs FIM transformation on a single example (list of tokens)
+ """
+ if np_rng.binomial(1, args.fim_rate):
+ boundaries = sorted(np_rng.randint(low=0, high=len(example) + 1, size=2))
+
+ prefix = example[: boundaries[0]]
+ middle = example[boundaries[0] : boundaries[1]]
+ suffix = example[boundaries[1] :]
+
+ if args.truncate_or_pad:
+ total_length = len(prefix) + len(middle) + len(suffix) + 3
+ diff = total_length - len(example)
+ if diff > 0:
+ suffix = suffix[: max(0, len(suffix) - diff)]
+ elif diff < 0:
+ suffix.extend([pad_tok_id] * (-diff))
+
+ if np_rng.binomial(1, args.fim_spm_rate):
+ # Apply Suffix-Prefix-Middle (SPM) transformation
+ transformed_example = [prefix_tok_id, suffix_tok_id] + suffix + [middle_tok_id] + prefix + middle
+ else:
+ # Apply Prefix-Suffix-Middle (PSM) transformation
+ transformed_example = [prefix_tok_id] + prefix + [suffix_tok_id] + suffix + [middle_tok_id] + middle
+ else:
+ transformed_example = example
+
+ return transformed_example
+
+ # Below function is the one you are supposed to call in the .map() function
+ def apply_fim(examples):
+ """
+ Apply FIM transformation to a batch of examples
+ """
+ fim_transform_ids = [fim_transform(ids) for ids in examples["input_ids"]]
+ examples["input_ids"] = fim_transform_ids
+ examples["labels"] = fim_transform_ids
+ # If your application requires custom attention mask, please adjust this function's below line.
+ # Since FIM transformation increases the number of tokens in input_ids and labels
+ # but leaves the number of tokens unchanged in attention_masks which would cause problems
+ examples["attention_mask"] = [[1] * len(mask) for mask in examples["input_ids"]]
+ return examples
+
+ # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
+ # for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
+ # to preprocess.
+ #
+ # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
+ # https://huggingface.co/docs/datasets/process#map
+
+ # FIM transformations are only supposed to be applied before group_texts processing otherwise some sentences will
+ # have 3-4 more tokens than others due to probabilistic addition of FIM-specific tokens which will raise errors
+ with accelerator.main_process_first():
+ fim_datasets = tokenized_datasets.map(
+ apply_fim,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Performing FIM transformation",
+ )
+ lm_datasets = fim_datasets.map(
+ group_texts,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ load_from_cache_file=not args.overwrite_cache,
+ desc=f"Grouping texts in chunks of {block_size}",
+ )
+
+ train_dataset = lm_datasets["train"]
+ eval_dataset = lm_datasets["validation"]
+
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ # DataLoaders creation:
+ train_dataloader = DataLoader(
+ train_dataset, shuffle=True, collate_fn=default_data_collator, batch_size=args.per_device_train_batch_size
+ )
+ eval_dataloader = DataLoader(
+ eval_dataset, collate_fn=default_data_collator, batch_size=args.per_device_eval_batch_size
+ )
+
+ # Optimizer
+ # Split weights in two groups, one with weight decay and the other not.
+ no_decay = ["bias", "layer_norm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps * args.gradient_accumulation_steps,
+ num_training_steps=args.max_train_steps * args.gradient_accumulation_steps,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # On TPU, the tie weights in our model have been disconnected, so we need to restore the ties.
+ if accelerator.distributed_type == DistributedType.TPU:
+ model.tie_weights()
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("fim_no_trainer", experiment_config)
+
+ # Train!
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ checkpoint_path = args.resume_from_checkpoint
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ checkpoint_path = path
+ path = os.path.basename(checkpoint_path)
+
+ accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
+ accelerator.load_state(checkpoint_path)
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ completed_steps = resume_step // args.gradient_accumulation_steps
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We skip the first `n` batches in the dataloader when resuming from a checkpoint
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ with accelerator.accumulate(model):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # Checks if the accelerator has performed an optimization step behind the scenes
+ if accelerator.sync_gradients:
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+ if completed_steps >= args.max_train_steps:
+ break
+
+ model.eval()
+ losses = []
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+
+ loss = outputs.loss
+ losses.append(accelerator.gather_for_metrics(loss.repeat(args.per_device_eval_batch_size)))
+
+ losses = torch.cat(losses)
+ try:
+ eval_loss = torch.mean(losses)
+ perplexity = math.exp(eval_loss)
+ except OverflowError:
+ perplexity = float("inf")
+
+ logger.info(f"epoch {epoch}: perplexity: {perplexity} eval_loss: {eval_loss}")
+
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "perplexity": perplexity,
+ "eval_loss": eval_loss,
+ "train_loss": total_loss.item() / len(train_dataloader),
+ "epoch": epoch,
+ "step": completed_steps,
+ },
+ step=completed_steps,
+ )
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ repo.push_to_hub(
+ commit_message=f"Training in progress epoch {epoch}", blocking=False, auto_lfs_prune=True
+ )
+
+ if args.checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.with_tracking:
+ accelerator.end_training()
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ if args.push_to_hub:
+ repo.push_to_hub(commit_message="End of training", auto_lfs_prune=True)
+
+ with open(os.path.join(args.output_dir, "all_results.json"), "w") as f:
+ json.dump({"perplexity": perplexity}, f)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_mlm.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_mlm.py
new file mode 100644
index 0000000000000000000000000000000000000000..fde2980d3ab5b83e6a92eda6b264c346890d3629
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_mlm.py
@@ -0,0 +1,691 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2020 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for masked language modeling (BERT, ALBERT, RoBERTa...) on a text file or a dataset.
+
+Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
+https://huggingface.co/models?filter=fill-mask
+"""
+# You can also adapt this script on your own masked language modeling task. Pointers for this are left as comments.
+
+import logging
+import math
+import os
+import sys
+from dataclasses import dataclass, field
+from itertools import chain
+from typing import Optional
+
+import datasets
+import evaluate
+import torch
+from datasets import load_dataset
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ MODEL_FOR_MASKED_LM_MAPPING,
+ AutoConfig,
+ AutoModelForMaskedLM,
+ AutoTokenizer,
+ DataCollatorForLanguageModeling,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ is_torch_xla_available,
+ set_seed,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
+
+logger = logging.getLogger(__name__)
+MODEL_CONFIG_CLASSES = list(MODEL_FOR_MASKED_LM_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ model_name_or_path: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
+ )
+ },
+ )
+ model_type: Optional[str] = field(
+ default=None,
+ metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
+ )
+ config_overrides: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Override some existing default config settings when a model is trained from scratch. Example: "
+ "n_embd=10,resid_pdrop=0.2,scale_attn_weights=false,summary_type=cls_index"
+ )
+ },
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ torch_dtype: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Override the default `torch.dtype` and load the model under this dtype. If `auto` is passed, the "
+ "dtype will be automatically derived from the model's weights."
+ ),
+ "choices": ["auto", "bfloat16", "float16", "float32"],
+ },
+ )
+ low_cpu_mem_usage: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "It is an option to create the model as an empty shell, then only materialize its parameters when the pretrained weights are loaded. "
+ "set True will benefit LLM loading time and RAM consumption."
+ )
+ },
+ )
+
+ def __post_init__(self):
+ if self.config_overrides is not None and (self.config_name is not None or self.model_name_or_path is not None):
+ raise ValueError(
+ "--config_overrides can't be used in combination with --config_name or --model_name_or_path"
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ validation_split_percentage: Optional[int] = field(
+ default=5,
+ metadata={
+ "help": "The percentage of the train set used as validation set in case there's no validation split"
+ },
+ )
+ max_seq_length: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated."
+ )
+ },
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ mlm_probability: float = field(
+ default=0.15, metadata={"help": "Ratio of tokens to mask for masked language modeling loss"}
+ )
+ line_by_line: bool = field(
+ default=False,
+ metadata={"help": "Whether distinct lines of text in the dataset are to be handled as distinct sequences."},
+ )
+ pad_to_max_length: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to pad all samples to `max_seq_length`. "
+ "If False, will pad the samples dynamically when batching to the maximum length in the batch."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ streaming: bool = field(default=False, metadata={"help": "Enable streaming mode"})
+
+ def __post_init__(self):
+ if self.streaming:
+ require_version("datasets>=2.0.0", "The streaming feature requires `datasets>=2.0.0`")
+
+ if self.dataset_name is None and self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ if extension not in ["csv", "json", "txt"]:
+ raise ValueError("`train_file` should be a csv, a json or a txt file.")
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ if extension not in ["csv", "json", "txt"]:
+ raise ValueError("`validation_file` should be a csv, a json or a txt file.")
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_mlm", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ datasets.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column. You can easily tweak this
+ # behavior (see below)
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ streaming=data_args.streaming,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ streaming=data_args.streaming,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ raw_datasets["train"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ streaming=data_args.streaming,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ if extension == "txt":
+ extension = "text"
+ raw_datasets = load_dataset(
+ extension,
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+
+ # If no validation data is there, validation_split_percentage will be used to divide the dataset.
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ raw_datasets["train"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config_kwargs = {
+ "cache_dir": model_args.cache_dir,
+ "revision": model_args.model_revision,
+ "token": model_args.token,
+ "trust_remote_code": model_args.trust_remote_code,
+ }
+ if model_args.config_name:
+ config = AutoConfig.from_pretrained(model_args.config_name, **config_kwargs)
+ elif model_args.model_name_or_path:
+ config = AutoConfig.from_pretrained(model_args.model_name_or_path, **config_kwargs)
+ else:
+ config = CONFIG_MAPPING[model_args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+ if model_args.config_overrides is not None:
+ logger.info(f"Overriding config: {model_args.config_overrides}")
+ config.update_from_string(model_args.config_overrides)
+ logger.info(f"New config: {config}")
+
+ tokenizer_kwargs = {
+ "cache_dir": model_args.cache_dir,
+ "use_fast": model_args.use_fast_tokenizer,
+ "revision": model_args.model_revision,
+ "token": model_args.token,
+ "trust_remote_code": model_args.trust_remote_code,
+ }
+ if model_args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(model_args.tokenizer_name, **tokenizer_kwargs)
+ elif model_args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(model_args.model_name_or_path, **tokenizer_kwargs)
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if model_args.model_name_or_path:
+ torch_dtype = (
+ model_args.torch_dtype
+ if model_args.torch_dtype in ["auto", None]
+ else getattr(torch, model_args.torch_dtype)
+ )
+ model = AutoModelForMaskedLM.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ torch_dtype=torch_dtype,
+ low_cpu_mem_usage=model_args.low_cpu_mem_usage,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = AutoModelForMaskedLM.from_config(config, trust_remote_code=model_args.trust_remote_code)
+
+ # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
+ # on a small vocab and want a smaller embedding size, remove this test.
+ embedding_size = model.get_input_embeddings().weight.shape[0]
+ if len(tokenizer) > embedding_size:
+ model.resize_token_embeddings(len(tokenizer))
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ if training_args.do_train:
+ column_names = list(raw_datasets["train"].features)
+ else:
+ column_names = list(raw_datasets["validation"].features)
+ text_column_name = "text" if "text" in column_names else column_names[0]
+
+ if data_args.max_seq_length is None:
+ max_seq_length = tokenizer.model_max_length
+ if max_seq_length > 1024:
+ logger.warning(
+ "The chosen tokenizer supports a `model_max_length` that is longer than the default `block_size` value"
+ " of 1024. If you would like to use a longer `block_size` up to `tokenizer.model_max_length` you can"
+ " override this default with `--block_size xxx`."
+ )
+ max_seq_length = 1024
+ else:
+ if data_args.max_seq_length > tokenizer.model_max_length:
+ logger.warning(
+ f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
+ f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
+ )
+ max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
+
+ if data_args.line_by_line:
+ # When using line_by_line, we just tokenize each nonempty line.
+ padding = "max_length" if data_args.pad_to_max_length else False
+
+ def tokenize_function(examples):
+ # Remove empty lines
+ examples[text_column_name] = [
+ line for line in examples[text_column_name] if len(line) > 0 and not line.isspace()
+ ]
+ return tokenizer(
+ examples[text_column_name],
+ padding=padding,
+ truncation=True,
+ max_length=max_seq_length,
+ # We use this option because DataCollatorForLanguageModeling (see below) is more efficient when it
+ # receives the `special_tokens_mask`.
+ return_special_tokens_mask=True,
+ )
+
+ with training_args.main_process_first(desc="dataset map tokenization"):
+ if not data_args.streaming:
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=[text_column_name],
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on dataset line_by_line",
+ )
+ else:
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=[text_column_name],
+ )
+ else:
+ # Otherwise, we tokenize every text, then concatenate them together before splitting them in smaller parts.
+ # We use `return_special_tokens_mask=True` because DataCollatorForLanguageModeling (see below) is more
+ # efficient when it receives the `special_tokens_mask`.
+ def tokenize_function(examples):
+ return tokenizer(examples[text_column_name], return_special_tokens_mask=True)
+
+ with training_args.main_process_first(desc="dataset map tokenization"):
+ if not data_args.streaming:
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on every text in dataset",
+ )
+ else:
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ remove_columns=column_names,
+ )
+
+ # Main data processing function that will concatenate all texts from our dataset and generate chunks of
+ # max_seq_length.
+ def group_texts(examples):
+ # Concatenate all texts.
+ concatenated_examples = {k: list(chain(*examples[k])) for k in examples.keys()}
+ total_length = len(concatenated_examples[list(examples.keys())[0]])
+ # We drop the small remainder, and if the total_length < max_seq_length we exclude this batch and return an empty dict.
+ # We could add padding if the model supported it instead of this drop, you can customize this part to your needs.
+ total_length = (total_length // max_seq_length) * max_seq_length
+ # Split by chunks of max_len.
+ result = {
+ k: [t[i : i + max_seq_length] for i in range(0, total_length, max_seq_length)]
+ for k, t in concatenated_examples.items()
+ }
+ return result
+
+ # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a
+ # remainder for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value
+ # might be slower to preprocess.
+ #
+ # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
+ # https://huggingface.co/docs/datasets/process#map
+
+ with training_args.main_process_first(desc="grouping texts together"):
+ if not data_args.streaming:
+ tokenized_datasets = tokenized_datasets.map(
+ group_texts,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc=f"Grouping texts in chunks of {max_seq_length}",
+ )
+ else:
+ tokenized_datasets = tokenized_datasets.map(
+ group_texts,
+ batched=True,
+ )
+
+ if training_args.do_train:
+ if "train" not in tokenized_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = tokenized_datasets["train"]
+ if data_args.max_train_samples is not None:
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+
+ if training_args.do_eval:
+ if "validation" not in tokenized_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_dataset = tokenized_datasets["validation"]
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+
+ def preprocess_logits_for_metrics(logits, labels):
+ if isinstance(logits, tuple):
+ # Depending on the model and config, logits may contain extra tensors,
+ # like past_key_values, but logits always come first
+ logits = logits[0]
+ return logits.argmax(dim=-1)
+
+ metric = evaluate.load("accuracy", cache_dir=model_args.cache_dir)
+
+ def compute_metrics(eval_preds):
+ preds, labels = eval_preds
+ # preds have the same shape as the labels, after the argmax(-1) has been calculated
+ # by preprocess_logits_for_metrics
+ labels = labels.reshape(-1)
+ preds = preds.reshape(-1)
+ mask = labels != -100
+ labels = labels[mask]
+ preds = preds[mask]
+ return metric.compute(predictions=preds, references=labels)
+
+ # Data collator
+ # This one will take care of randomly masking the tokens.
+ pad_to_multiple_of_8 = data_args.line_by_line and training_args.fp16 and not data_args.pad_to_max_length
+ data_collator = DataCollatorForLanguageModeling(
+ tokenizer=tokenizer,
+ mlm_probability=data_args.mlm_probability,
+ pad_to_multiple_of=8 if pad_to_multiple_of_8 else None,
+ )
+
+ # Initialize our Trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset if training_args.do_train else None,
+ eval_dataset=eval_dataset if training_args.do_eval else None,
+ processing_class=tokenizer,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics if training_args.do_eval and not is_torch_xla_available() else None,
+ preprocess_logits_for_metrics=preprocess_logits_for_metrics
+ if training_args.do_eval and not is_torch_xla_available()
+ else None,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model() # Saves the tokenizer too for easy upload
+ metrics = train_result.metrics
+
+ max_train_samples = (
+ data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
+ )
+ metrics["train_samples"] = min(max_train_samples, len(train_dataset))
+
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+
+ metrics = trainer.evaluate()
+
+ max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
+ metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
+ try:
+ perplexity = math.exp(metrics["eval_loss"])
+ except OverflowError:
+ perplexity = float("inf")
+ metrics["perplexity"] = perplexity
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "fill-mask"}
+ if data_args.dataset_name is not None:
+ kwargs["dataset_tags"] = data_args.dataset_name
+ if data_args.dataset_config_name is not None:
+ kwargs["dataset_args"] = data_args.dataset_config_name
+ kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
+ else:
+ kwargs["dataset"] = data_args.dataset_name
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_mlm_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_mlm_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..40265efcfdae2901c5c11d779114c90bd1dd71ce
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_mlm_no_trainer.py
@@ -0,0 +1,763 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for masked language modeling (BERT, ALBERT, RoBERTa...)
+on a text file or a dataset without using HuggingFace Trainer.
+
+Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
+https://huggingface.co/models?filter=fill-mask
+"""
+# You can also adapt this script on your own mlm task. Pointers for this are left as comments.
+
+import argparse
+import json
+import logging
+import math
+import os
+import random
+from itertools import chain
+from pathlib import Path
+
+import datasets
+import torch
+from accelerate import Accelerator, DistributedType
+from accelerate.logging import get_logger
+from accelerate.utils import set_seed
+from datasets import load_dataset
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from tqdm.auto import tqdm
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ MODEL_MAPPING,
+ AutoConfig,
+ AutoModelForMaskedLM,
+ AutoTokenizer,
+ DataCollatorForLanguageModeling,
+ SchedulerType,
+ get_scheduler,
+)
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+logger = get_logger(__name__)
+require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
+MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Finetune a transformers model on a Masked Language Modeling task")
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ default=None,
+ help="The name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--dataset_config_name",
+ type=str,
+ default=None,
+ help="The configuration name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
+ )
+ parser.add_argument(
+ "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
+ )
+ parser.add_argument(
+ "--validation_split_percentage",
+ default=5,
+ help="The percentage of the train set used as validation set in case there's no validation split",
+ )
+ parser.add_argument(
+ "--pad_to_max_length",
+ action="store_true",
+ help="If passed, pad all samples to `max_length`. Otherwise, dynamic padding is used.",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=False,
+ )
+ parser.add_argument(
+ "--config_name",
+ type=str,
+ default=None,
+ help="Pretrained config name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ type=str,
+ default=None,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--use_slow_tokenizer",
+ action="store_true",
+ help="If passed, will use a slow tokenizer (not backed by the 🤗 Tokenizers library).",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument(
+ "--model_type",
+ type=str,
+ default=None,
+ help="Model type to use if training from scratch.",
+ choices=MODEL_TYPES,
+ )
+ parser.add_argument(
+ "--max_seq_length",
+ type=int,
+ default=None,
+ help=(
+ "The maximum total input sequence length after tokenization. Sequences longer than this will be truncated."
+ ),
+ )
+ parser.add_argument(
+ "--line_by_line",
+ type=bool,
+ default=False,
+ help="Whether distinct lines of text in the dataset are to be handled as distinct sequences.",
+ )
+ parser.add_argument(
+ "--preprocessing_num_workers",
+ type=int,
+ default=None,
+ help="The number of processes to use for the preprocessing.",
+ )
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+ parser.add_argument(
+ "--mlm_probability", type=float, default=0.15, help="Ratio of tokens to mask for masked language modeling loss"
+ )
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--trust_remote_code",
+ action="store_true",
+ help=(
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ parser.add_argument(
+ "--low_cpu_mem_usage",
+ action="store_true",
+ help=(
+ "It is an option to create the model as an empty shell, then only materialize its parameters when the pretrained weights are loaded. "
+ "If passed, LLM loading time and RAM consumption will be benefited."
+ ),
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+ if args.dataset_name is None and args.train_file is None and args.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if args.train_file is not None:
+ extension = args.train_file.split(".")[-1]
+ if extension not in ["csv", "json", "txt"]:
+ raise ValueError("`train_file` should be a csv, json or txt file.")
+ if args.validation_file is not None:
+ extension = args.validation_file.split(".")[-1]
+ if extension not in ["csv", "json", "txt"]:
+ raise ValueError("`validation_file` should be a csv, json or txt file.")
+
+ if args.push_to_hub:
+ if args.output_dir is None:
+ raise ValueError("Need an `output_dir` to create a repo when `--push_to_hub` is passed.")
+
+ return args
+
+
+def main():
+ args = parse_args()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_mlm_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+ accelerator_log_kwargs = {}
+
+ if args.with_tracking:
+ accelerator_log_kwargs["log_with"] = args.report_to
+ accelerator_log_kwargs["project_dir"] = args.output_dir
+
+ accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
+ )
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ args.dataset_name,
+ args.dataset_config_name,
+ split=f"train[:{args.validation_split_percentage}%]",
+ trust_remote_code=args.trust_remote_code,
+ )
+ raw_datasets["train"] = load_dataset(
+ args.dataset_name,
+ args.dataset_config_name,
+ split=f"train[{args.validation_split_percentage}%:]",
+ trust_remote_code=args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if args.train_file is not None:
+ data_files["train"] = args.train_file
+ extension = args.train_file.split(".")[-1]
+ if args.validation_file is not None:
+ data_files["validation"] = args.validation_file
+ extension = args.validation_file.split(".")[-1]
+ if extension == "txt":
+ extension = "text"
+ raw_datasets = load_dataset(extension, data_files=data_files)
+ # If no validation data is there, validation_split_percentage will be used to divide the dataset.
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[:{args.validation_split_percentage}%]",
+ )
+ raw_datasets["train"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[{args.validation_split_percentage}%:]",
+ )
+
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+ #
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ if args.config_name:
+ config = AutoConfig.from_pretrained(args.config_name, trust_remote_code=args.trust_remote_code)
+ elif args.model_name_or_path:
+ config = AutoConfig.from_pretrained(args.model_name_or_path, trust_remote_code=args.trust_remote_code)
+ else:
+ config = CONFIG_MAPPING[args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ if args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.tokenizer_name, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
+ )
+ elif args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.model_name_or_path, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
+ )
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if args.model_name_or_path:
+ model = AutoModelForMaskedLM.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ low_cpu_mem_usage=args.low_cpu_mem_usage,
+ trust_remote_code=args.trust_remote_code,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = AutoModelForMaskedLM.from_config(config, trust_remote_code=args.trust_remote_code)
+
+ # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
+ # on a small vocab and want a smaller embedding size, remove this test.
+ embedding_size = model.get_input_embeddings().weight.shape[0]
+ if len(tokenizer) > embedding_size:
+ model.resize_token_embeddings(len(tokenizer))
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ column_names = raw_datasets["train"].column_names
+ text_column_name = "text" if "text" in column_names else column_names[0]
+
+ if args.max_seq_length is None:
+ max_seq_length = tokenizer.model_max_length
+ if max_seq_length > 1024:
+ logger.warning(
+ "The chosen tokenizer supports a `model_max_length` that is longer than the default `block_size` value"
+ " of 1024. If you would like to use a longer `block_size` up to `tokenizer.model_max_length` you can"
+ " override this default with `--block_size xxx`."
+ )
+ max_seq_length = 1024
+ else:
+ if args.max_seq_length > tokenizer.model_max_length:
+ logger.warning(
+ f"The max_seq_length passed ({args.max_seq_length}) is larger than the maximum length for the "
+ f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
+ )
+ max_seq_length = min(args.max_seq_length, tokenizer.model_max_length)
+
+ if args.line_by_line:
+ # When using line_by_line, we just tokenize each nonempty line.
+ padding = "max_length" if args.pad_to_max_length else False
+
+ def tokenize_function(examples):
+ # Remove empty lines
+ examples[text_column_name] = [
+ line for line in examples[text_column_name] if len(line) > 0 and not line.isspace()
+ ]
+ return tokenizer(
+ examples[text_column_name],
+ padding=padding,
+ truncation=True,
+ max_length=max_seq_length,
+ # We use this option because DataCollatorForLanguageModeling (see below) is more efficient when it
+ # receives the `special_tokens_mask`.
+ return_special_tokens_mask=True,
+ )
+
+ with accelerator.main_process_first():
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=[text_column_name],
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Running tokenizer on dataset line_by_line",
+ )
+ else:
+ # Otherwise, we tokenize every text, then concatenate them together before splitting them in smaller parts.
+ # We use `return_special_tokens_mask=True` because DataCollatorForLanguageModeling (see below) is more
+ # efficient when it receives the `special_tokens_mask`.
+ def tokenize_function(examples):
+ return tokenizer(examples[text_column_name], return_special_tokens_mask=True)
+
+ with accelerator.main_process_first():
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Running tokenizer on every text in dataset",
+ )
+
+ # Main data processing function that will concatenate all texts from our dataset and generate chunks of
+ # max_seq_length.
+ def group_texts(examples):
+ # Concatenate all texts.
+ concatenated_examples = {k: list(chain(*examples[k])) for k in examples.keys()}
+ total_length = len(concatenated_examples[list(examples.keys())[0]])
+ # We drop the small remainder, and if the total_length < max_seq_length we exclude this batch and return an empty dict.
+ # We could add padding if the model supported it instead of this drop, you can customize this part to your needs.
+ total_length = (total_length // max_seq_length) * max_seq_length
+ # Split by chunks of max_len.
+ result = {
+ k: [t[i : i + max_seq_length] for i in range(0, total_length, max_seq_length)]
+ for k, t in concatenated_examples.items()
+ }
+ return result
+
+ # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a
+ # remainder for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value
+ # might be slower to preprocess.
+ #
+ # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
+ # https://huggingface.co/docs/datasets/process#map
+
+ with accelerator.main_process_first():
+ tokenized_datasets = tokenized_datasets.map(
+ group_texts,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ load_from_cache_file=not args.overwrite_cache,
+ desc=f"Grouping texts in chunks of {max_seq_length}",
+ )
+
+ train_dataset = tokenized_datasets["train"]
+ eval_dataset = tokenized_datasets["validation"]
+
+ # Conditional for small test subsets
+ if len(train_dataset) > 3:
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ # Data collator
+ # This one will take care of randomly masking the tokens.
+ data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=args.mlm_probability)
+
+ # DataLoaders creation:
+ train_dataloader = DataLoader(
+ train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
+ )
+ eval_dataloader = DataLoader(eval_dataset, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size)
+
+ # Optimizer
+ # Split weights in two groups, one with weight decay and the other not.
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
+
+ # Note -> the training dataloader needs to be prepared before we grab his length below (cause its length will be
+ # shorter in multiprocess)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
+ num_training_steps=args.max_train_steps
+ if overrode_max_train_steps
+ else args.max_train_steps * accelerator.num_processes,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # On TPU, the tie weights in our model have been disconnected, so we need to restore the ties.
+ if accelerator.distributed_type == DistributedType.TPU:
+ model.tie_weights()
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("mlm_no_trainer", experiment_config)
+
+ # Train!
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ checkpoint_path = args.resume_from_checkpoint
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ checkpoint_path = path
+ path = os.path.basename(checkpoint_path)
+
+ accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
+ accelerator.load_state(checkpoint_path)
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ completed_steps = resume_step // args.gradient_accumulation_steps
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We skip the first `n` batches in the dataloader when resuming from a checkpoint
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ with accelerator.accumulate(model):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # Checks if the accelerator has performed an optimization step behind the scenes
+ if accelerator.sync_gradients:
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if completed_steps >= args.max_train_steps:
+ break
+
+ model.eval()
+ losses = []
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+
+ loss = outputs.loss
+ losses.append(accelerator.gather_for_metrics(loss.repeat(args.per_device_eval_batch_size)))
+
+ losses = torch.cat(losses)
+ try:
+ eval_loss = torch.mean(losses)
+ perplexity = math.exp(eval_loss)
+ except OverflowError:
+ perplexity = float("inf")
+
+ logger.info(f"epoch {epoch}: perplexity: {perplexity} eval_loss: {eval_loss}")
+
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "perplexity": perplexity,
+ "eval_loss": eval_loss,
+ "train_loss": total_loss.item() / len(train_dataloader),
+ "epoch": epoch,
+ "step": completed_steps,
+ },
+ step=completed_steps,
+ )
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if args.checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.with_tracking:
+ accelerator.end_training()
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ if args.push_to_hub:
+ api.upload_folder(
+ commit_message="End of training",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+ with open(os.path.join(args.output_dir, "all_results.json"), "w") as f:
+ json.dump({"perplexity": perplexity}, f)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_plm.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_plm.py
new file mode 100644
index 0000000000000000000000000000000000000000..6ef17ebb9b6af8991a6987046d02c7e25a740555
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/language-modeling/run_plm.py
@@ -0,0 +1,584 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2020 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for permutation language modeling.
+"""
+# You can also adapt this script on your own permutation language modeling task. Pointers for this are left as comments.
+
+import logging
+import math
+import os
+import sys
+from dataclasses import dataclass, field
+from itertools import chain
+from typing import Optional
+
+import datasets
+from datasets import load_dataset
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoTokenizer,
+ DataCollatorForPermutationLanguageModeling,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ XLNetConfig,
+ XLNetLMHeadModel,
+ set_seed,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ model_name_or_path: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
+ )
+ },
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ config_overrides: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Override some existing default config settings when a model is trained from scratch. Example: "
+ "n_embd=10,resid_pdrop=0.2,scale_attn_weights=false,summary_type=cls_index"
+ )
+ },
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ low_cpu_mem_usage: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "It is an option to create the model as an empty shell, then only materialize its parameters when the pretrained weights are loaded. "
+ "set True will benefit LLM loading time and RAM consumption."
+ )
+ },
+ )
+
+ def __post_init__(self):
+ if self.config_overrides is not None and (self.config_name is not None or self.model_name_or_path is not None):
+ raise ValueError(
+ "--config_overrides can't be used in combination with --config_name or --model_name_or_path"
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ validation_split_percentage: Optional[int] = field(
+ default=5,
+ metadata={
+ "help": "The percentage of the train set used as validation set in case there's no validation split"
+ },
+ )
+ max_seq_length: int = field(
+ default=512,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated."
+ )
+ },
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ plm_probability: float = field(
+ default=1 / 6,
+ metadata={
+ "help": (
+ "Ratio of length of a span of masked tokens to surrounding context length for "
+ "permutation language modeling."
+ )
+ },
+ )
+ max_span_length: int = field(
+ default=5, metadata={"help": "Maximum length of a span of masked tokens for permutation language modeling."}
+ )
+ line_by_line: bool = field(
+ default=False,
+ metadata={"help": "Whether distinct lines of text in the dataset are to be handled as distinct sequences."},
+ )
+ pad_to_max_length: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to pad all samples to `max_seq_length`. "
+ "If False, will pad the samples dynamically when batching to the maximum length in the batch."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+
+ def __post_init__(self):
+ if self.dataset_name is None and self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, a json or a txt file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, a json or a txt file."
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_plm", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ datasets.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+ raw_datasets["train"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ if extension == "txt":
+ extension = "text"
+ raw_datasets = load_dataset(extension, data_files=data_files, cache_dir=model_args.cache_dir)
+ # If no validation data is there, validation_split_percentage will be used to divide the dataset.
+ if "validation" not in raw_datasets.keys():
+ raw_datasets["validation"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[:{data_args.validation_split_percentage}%]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ raw_datasets["train"] = load_dataset(
+ extension,
+ data_files=data_files,
+ split=f"train[{data_args.validation_split_percentage}%:]",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config_kwargs = {
+ "cache_dir": model_args.cache_dir,
+ "revision": model_args.model_revision,
+ "token": model_args.token,
+ }
+ if model_args.config_name:
+ config = AutoConfig.from_pretrained(model_args.config_name, **config_kwargs)
+ elif model_args.model_name_or_path:
+ config = AutoConfig.from_pretrained(model_args.model_name_or_path, **config_kwargs)
+ else:
+ config = XLNetConfig()
+ logger.warning("You are instantiating a new config instance from scratch.")
+ if model_args.config_overrides is not None:
+ logger.info(f"Overriding config: {model_args.config_overrides}")
+ config.update_from_string(model_args.config_overrides)
+ logger.info(f"New config: {config}")
+
+ tokenizer_kwargs = {
+ "cache_dir": model_args.cache_dir,
+ "use_fast": model_args.use_fast_tokenizer,
+ "revision": model_args.model_revision,
+ "token": model_args.token,
+ }
+ if model_args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(model_args.tokenizer_name, **tokenizer_kwargs)
+ elif model_args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(model_args.model_name_or_path, **tokenizer_kwargs)
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if model_args.model_name_or_path:
+ model = XLNetLMHeadModel.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ low_cpu_mem_usage=model_args.low_cpu_mem_usage,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = XLNetLMHeadModel(config)
+
+ # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
+ # on a small vocab and want a smaller embedding size, remove this test.
+ embedding_size = model.get_input_embeddings().weight.shape[0]
+ if len(tokenizer) > embedding_size:
+ model.resize_token_embeddings(len(tokenizer))
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ if training_args.do_train:
+ column_names = raw_datasets["train"].column_names
+ else:
+ column_names = raw_datasets["validation"].column_names
+ text_column_name = "text" if "text" in column_names else column_names[0]
+
+ if data_args.max_seq_length > tokenizer.model_max_length:
+ logger.warning(
+ f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
+ f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
+ )
+ max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
+
+ if data_args.line_by_line:
+ # When using line_by_line, we just tokenize each nonempty line.
+ padding = "max_length" if data_args.pad_to_max_length else False
+
+ def tokenize_function(examples):
+ # Remove empty lines
+ examples["text"] = [line for line in examples["text"] if len(line) > 0 and not line.isspace()]
+ return tokenizer(examples["text"], padding=padding, truncation=True, max_length=max_seq_length)
+
+ with training_args.main_process_first(desc="dataset map tokenization"):
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=[text_column_name],
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on dataset line_by_line",
+ )
+ else:
+ # Otherwise, we tokenize every text, then concatenate them together before splitting them in smaller parts.
+ def tokenize_function(examples):
+ return tokenizer(examples[text_column_name])
+
+ with training_args.main_process_first(desc="dataset map tokenization"):
+ tokenized_datasets = raw_datasets.map(
+ tokenize_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on every text in dataset",
+ )
+
+ # Main data processing function that will concatenate all texts from our dataset and generate chunks of
+ # max_seq_length.
+ def group_texts(examples):
+ # Concatenate all texts.
+ concatenated_examples = {k: list(chain(*examples[k])) for k in examples.keys()}
+ total_length = len(concatenated_examples[list(examples.keys())[0]])
+ # We drop the small remainder, and if the total_length < max_seq_length we exclude this batch and return an empty dict.
+ # We could add padding if the model supported it instead of this drop, you can customize this part to your needs.
+ total_length = (total_length // max_seq_length) * max_seq_length
+ # Split by chunks of max_len.
+ result = {
+ k: [t[i : i + max_seq_length] for i in range(0, total_length, max_seq_length)]
+ for k, t in concatenated_examples.items()
+ }
+ return result
+
+ # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a
+ # remainder for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value
+ # might be slower to preprocess.
+ #
+ # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
+ # https://huggingface.co/docs/datasets/process#map
+
+ with training_args.main_process_first(desc="grouping texts together"):
+ tokenized_datasets = tokenized_datasets.map(
+ group_texts,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc=f"Grouping texts in chunks of {max_seq_length}",
+ )
+
+ if training_args.do_train:
+ if "train" not in tokenized_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = tokenized_datasets["train"]
+ if data_args.max_train_samples is not None:
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+
+ if training_args.do_eval:
+ if "validation" not in tokenized_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_dataset = tokenized_datasets["validation"]
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+
+ # Data collator
+ data_collator = DataCollatorForPermutationLanguageModeling(
+ tokenizer=tokenizer,
+ plm_probability=data_args.plm_probability,
+ max_span_length=data_args.max_span_length,
+ )
+
+ # Initialize our Trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset if training_args.do_train else None,
+ eval_dataset=eval_dataset if training_args.do_eval else None,
+ processing_classtokenizer=tokenizer,
+ data_collator=data_collator,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model() # Saves the tokenizer too for easy upload
+ metrics = train_result.metrics
+
+ max_train_samples = (
+ data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
+ )
+ metrics["train_samples"] = min(max_train_samples, len(train_dataset))
+
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+
+ metrics = trainer.evaluate()
+
+ max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
+ metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
+ try:
+ perplexity = math.exp(metrics["eval_loss"])
+ except OverflowError:
+ perplexity = float("inf")
+ metrics["perplexity"] = perplexity
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "language-modeling"}
+ if data_args.dataset_name is not None:
+ kwargs["dataset_tags"] = data_args.dataset_name
+ if data_args.dataset_config_name is not None:
+ kwargs["dataset_args"] = data_args.dataset_config_name
+ kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
+ else:
+ kwargs["dataset"] = data_args.dataset_name
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/multiple-choice/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/multiple-choice/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..118234002c88a3409216c87716cbee9d67fa03f6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/multiple-choice/README.md
@@ -0,0 +1,108 @@
+
+
+# Multiple Choice
+
+## Fine-tuning on SWAG with the Trainer
+
+`run_swag` allows you to fine-tune any model from our [hub](https://huggingface.co/models) (as long as its architecture as a `ForMultipleChoice` version in the library) on the SWAG dataset or your own csv/jsonlines files as long as they are structured the same way. To make it works on another dataset, you will need to tweak the `preprocess_function` inside the script.
+
+```bash
+python examples/multiple-choice/run_swag.py \
+--model_name_or_path FacebookAI/roberta-base \
+--do_train \
+--do_eval \
+--learning_rate 5e-5 \
+--num_train_epochs 3 \
+--output_dir /tmp/swag_base \
+--per_device_eval_batch_size=16 \
+--per_device_train_batch_size=16 \
+--overwrite_output
+```
+Training with the defined hyper-parameters yields the following results:
+```
+***** Eval results *****
+eval_acc = 0.8338998300509847
+eval_loss = 0.44457291918821606
+```
+
+## With Accelerate
+
+Based on the script [run_swag_no_trainer.py](https://github.com/huggingface/transformers/blob/main/examples/pytorch/multiple-choice/run_swag_no_trainer.py).
+
+Like `run_swag.py`, this script allows you to fine-tune any of the models on the [hub](https://huggingface.co/models) (as long as its architecture as a `ForMultipleChoice` version in the library) on
+the SWAG dataset or your own data in a csv or a JSON file. The main difference is that this
+script exposes the bare training loop, to allow you to quickly experiment and add any customization you would like.
+
+It offers less options than the script with `Trainer` (but you can easily change the options for the optimizer
+or the dataloaders directly in the script) but still run in a distributed setup, on TPU and supports mixed precision by
+the mean of the [🤗 `Accelerate`](https://github.com/huggingface/accelerate) library. You can use the script normally
+after installing it:
+
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+then
+
+```bash
+export DATASET_NAME=swag
+
+python run_swag_no_trainer.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --dataset_name $DATASET_NAME \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 32 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$DATASET_NAME/
+```
+
+You can then use your usual launchers to run in it in a distributed environment, but the easiest way is to run
+
+```bash
+accelerate config
+```
+
+and reply to the questions asked. Then
+
+```bash
+accelerate test
+```
+
+that will check everything is ready for training. Finally, you can launch training with
+
+```bash
+export DATASET_NAME=swag
+
+accelerate launch run_swag_no_trainer.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --dataset_name $DATASET_NAME \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 32 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$DATASET_NAME/
+```
+
+This command is the same and will work for:
+
+- a CPU-only setup
+- a setup with one GPU
+- a distributed training with several GPUs (single or multi node)
+- a training on TPUs
+
+Note that this library is in alpha release so your feedback is more than welcome if you encounter any problem using it.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/multiple-choice/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/multiple-choice/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..3bbfaef38eab5fa5261008bd32769e615059d00e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/multiple-choice/requirements.txt
@@ -0,0 +1,5 @@
+accelerate >= 0.12.0
+sentencepiece != 0.1.92
+protobuf
+torch >= 1.3
+evaluate
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/multiple-choice/run_no_trainer.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/multiple-choice/run_no_trainer.sh
new file mode 100644
index 0000000000000000000000000000000000000000..4fd84f37ed63fa9b3ae2da1a140ef65d514e25cf
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/multiple-choice/run_no_trainer.sh
@@ -0,0 +1,19 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+accelerate launch run_swag_no_trainer.py \
+ --model_name_or_path bert-base-uncased \
+ --dataset_name swag \
+ --output_dir /tmp/test-swag-no-trainer \
+ --pad_to_max_length
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/multiple-choice/run_swag.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/multiple-choice/run_swag.py
new file mode 100644
index 0000000000000000000000000000000000000000..2d927f41978824239b873c893dcfbd23b151bd38
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/multiple-choice/run_swag.py
@@ -0,0 +1,500 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright The HuggingFace Team and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for multiple choice.
+"""
+# You can also adapt this script on your own multiple choice task. Pointers for this are left as comments.
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from itertools import chain
+from typing import Optional, Union
+
+import datasets
+import numpy as np
+import torch
+from datasets import load_dataset
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForMultipleChoice,
+ AutoTokenizer,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ default_data_collator,
+ set_seed,
+)
+from transformers.tokenization_utils_base import PreTrainedTokenizerBase
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import PaddingStrategy, check_min_version, send_example_telemetry
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether or not to allow for custom models defined on the Hub in their own modeling files. This option "
+ "should only be set to `True` for repositories you trust and in which you have read the code, as it will "
+ "execute code present on the Hub on your local machine."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ max_seq_length: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. If passed, sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ pad_to_max_length: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to pad all samples to the maximum sentence length. "
+ "If False, will pad the samples dynamically when batching to the maximum length in the batch. More "
+ "efficient on GPU but very bad for TPU."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+
+ def __post_init__(self):
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+
+
+@dataclass
+class DataCollatorForMultipleChoice:
+ """
+ Data collator that will dynamically pad the inputs for multiple choice received.
+
+ Args:
+ tokenizer ([`PreTrainedTokenizer`] or [`PreTrainedTokenizerFast`]):
+ The tokenizer used for encoding the data.
+ padding (`bool`, `str` or [`~utils.PaddingStrategy`], *optional*, defaults to `True`):
+ Select a strategy to pad the returned sequences (according to the model's padding side and padding index)
+ among:
+
+ - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single sequence
+ if provided).
+ - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum
+ acceptable input length for the model if that argument is not provided.
+ - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different
+ lengths).
+ max_length (`int`, *optional*):
+ Maximum length of the returned list and optionally padding length (see above).
+ pad_to_multiple_of (`int`, *optional*):
+ If set will pad the sequence to a multiple of the provided value.
+
+ This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability >=
+ 7.5 (Volta).
+ """
+
+ tokenizer: PreTrainedTokenizerBase
+ padding: Union[bool, str, PaddingStrategy] = True
+ max_length: Optional[int] = None
+ pad_to_multiple_of: Optional[int] = None
+
+ def __call__(self, features):
+ label_name = "label" if "label" in features[0].keys() else "labels"
+ labels = [feature.pop(label_name) for feature in features]
+ batch_size = len(features)
+ num_choices = len(features[0]["input_ids"])
+ flattened_features = [
+ [{k: v[i] for k, v in feature.items()} for i in range(num_choices)] for feature in features
+ ]
+ flattened_features = list(chain(*flattened_features))
+
+ batch = self.tokenizer.pad(
+ flattened_features,
+ padding=self.padding,
+ max_length=self.max_length,
+ pad_to_multiple_of=self.pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Un-flatten
+ batch = {k: v.view(batch_size, num_choices, -1) for k, v in batch.items()}
+ # Add back labels
+ batch["labels"] = torch.tensor(labels, dtype=torch.int64)
+ return batch
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_swag", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ datasets.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.train_file is not None or data_args.validation_file is not None:
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ raw_datasets = load_dataset(
+ extension,
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ else:
+ # Downloading and loading the swag dataset from the hub.
+ raw_datasets = load_dataset(
+ "swag",
+ "regular",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ model = AutoModelForMultipleChoice.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ # When using your own dataset or a different dataset from swag, you will probably need to change this.
+ ending_names = [f"ending{i}" for i in range(4)]
+ context_name = "sent1"
+ question_header_name = "sent2"
+
+ if data_args.max_seq_length is None:
+ max_seq_length = tokenizer.model_max_length
+ if max_seq_length > 1024:
+ logger.warning(
+ "The chosen tokenizer supports a `model_max_length` that is longer than the default `block_size` value"
+ " of 1024. If you would like to use a longer `block_size` up to `tokenizer.model_max_length` you can"
+ " override this default with `--block_size xxx`."
+ )
+ max_seq_length = 1024
+ else:
+ if data_args.max_seq_length > tokenizer.model_max_length:
+ logger.warning(
+ f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
+ f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
+ )
+ max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
+
+ # Preprocessing the datasets.
+ def preprocess_function(examples):
+ first_sentences = [[context] * 4 for context in examples[context_name]]
+ question_headers = examples[question_header_name]
+ second_sentences = [
+ [f"{header} {examples[end][i]}" for end in ending_names] for i, header in enumerate(question_headers)
+ ]
+
+ # Flatten out
+ first_sentences = list(chain(*first_sentences))
+ second_sentences = list(chain(*second_sentences))
+
+ # Tokenize
+ tokenized_examples = tokenizer(
+ first_sentences,
+ second_sentences,
+ truncation=True,
+ max_length=max_seq_length,
+ padding="max_length" if data_args.pad_to_max_length else False,
+ )
+ # Un-flatten
+ return {k: [v[i : i + 4] for i in range(0, len(v), 4)] for k, v in tokenized_examples.items()}
+
+ if training_args.do_train:
+ if "train" not in raw_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = raw_datasets["train"]
+ if data_args.max_train_samples is not None:
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+ with training_args.main_process_first(desc="train dataset map pre-processing"):
+ train_dataset = train_dataset.map(
+ preprocess_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ )
+
+ if training_args.do_eval:
+ if "validation" not in raw_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_dataset = raw_datasets["validation"]
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+ with training_args.main_process_first(desc="validation dataset map pre-processing"):
+ eval_dataset = eval_dataset.map(
+ preprocess_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ )
+
+ # Data collator
+ data_collator = (
+ default_data_collator
+ if data_args.pad_to_max_length
+ else DataCollatorForMultipleChoice(tokenizer=tokenizer, pad_to_multiple_of=8 if training_args.fp16 else None)
+ )
+
+ # Metric
+ def compute_metrics(eval_predictions):
+ predictions, label_ids = eval_predictions
+ preds = np.argmax(predictions, axis=1)
+ return {"accuracy": (preds == label_ids).astype(np.float32).mean().item()}
+
+ # Initialize our Trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset if training_args.do_train else None,
+ eval_dataset=eval_dataset if training_args.do_eval else None,
+ processing_class=tokenizer,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model() # Saves the tokenizer too for easy upload
+ metrics = train_result.metrics
+
+ max_train_samples = (
+ data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
+ )
+ metrics["train_samples"] = min(max_train_samples, len(train_dataset))
+
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+
+ metrics = trainer.evaluate()
+ max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
+ metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ kwargs = {
+ "finetuned_from": model_args.model_name_or_path,
+ "tasks": "multiple-choice",
+ "dataset_tags": "swag",
+ "dataset_args": "regular",
+ "dataset": "SWAG",
+ "language": "en",
+ }
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/multiple-choice/run_swag_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/multiple-choice/run_swag_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..9ec972d091c74b7d7feb2effc8446c212a32a930
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/multiple-choice/run_swag_no_trainer.py
@@ -0,0 +1,708 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright The HuggingFace Team and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning a 🤗 Transformers model on multiple choice relying on the accelerate library without using a Trainer.
+"""
+# You can also adapt this script on your own multiple choice task. Pointers for this are left as comments.
+
+import argparse
+import json
+import logging
+import math
+import os
+import random
+from dataclasses import dataclass
+from itertools import chain
+from pathlib import Path
+from typing import Optional, Union
+
+import datasets
+import evaluate
+import torch
+from accelerate import Accelerator
+from accelerate.logging import get_logger
+from accelerate.utils import set_seed
+from datasets import load_dataset
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from tqdm.auto import tqdm
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ MODEL_MAPPING,
+ AutoConfig,
+ AutoModelForMultipleChoice,
+ AutoTokenizer,
+ PreTrainedTokenizerBase,
+ SchedulerType,
+ default_data_collator,
+ get_scheduler,
+)
+from transformers.utils import PaddingStrategy, check_min_version, send_example_telemetry
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+logger = get_logger(__name__)
+# You should update this to your particular problem to have better documentation of `model_type`
+MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Finetune a transformers model on a multiple choice task")
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ default=None,
+ help="The name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--dataset_config_name",
+ type=str,
+ default=None,
+ help="The configuration name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
+ )
+ parser.add_argument(
+ "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
+ )
+ parser.add_argument(
+ "--max_seq_length",
+ type=int,
+ default=128,
+ help=(
+ "The maximum total input sequence length after tokenization. Sequences longer than this will be truncated,"
+ " sequences shorter will be padded if `--pad_to_max_length` is passed."
+ ),
+ )
+ parser.add_argument(
+ "--pad_to_max_length",
+ action="store_true",
+ help="If passed, pad all samples to `max_length`. Otherwise, dynamic padding is used.",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=False,
+ )
+ parser.add_argument(
+ "--config_name",
+ type=str,
+ default=None,
+ help="Pretrained config name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ type=str,
+ default=None,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--use_slow_tokenizer",
+ action="store_true",
+ help="If passed, will use a slow tokenizer (not backed by the 🤗 Tokenizers library).",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument(
+ "--model_type",
+ type=str,
+ default=None,
+ help="Model type to use if training from scratch.",
+ choices=MODEL_TYPES,
+ )
+ parser.add_argument(
+ "--debug",
+ action="store_true",
+ help="Activate debug mode and run training only with a subset of data.",
+ )
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--trust_remote_code",
+ action="store_true",
+ help=(
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ args = parser.parse_args()
+
+ if args.push_to_hub:
+ assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
+
+ return args
+
+
+@dataclass
+class DataCollatorForMultipleChoice:
+ """
+ Data collator that will dynamically pad the inputs for multiple choice received.
+
+ Args:
+ tokenizer ([`PreTrainedTokenizer`] or [`PreTrainedTokenizerFast`]):
+ The tokenizer used for encoding the data.
+ padding (`bool`, `str` or [`~utils.PaddingStrategy`], *optional*, defaults to `True`):
+ Select a strategy to pad the returned sequences (according to the model's padding side and padding index)
+ among:
+
+ - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single sequence
+ if provided).
+ - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum
+ acceptable input length for the model if that argument is not provided.
+ - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different
+ lengths).
+ max_length (`int`, *optional*):
+ Maximum length of the returned list and optionally padding length (see above).
+ pad_to_multiple_of (`int`, *optional*):
+ If set will pad the sequence to a multiple of the provided value.
+
+ This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability >=
+ 7.5 (Volta).
+ """
+
+ tokenizer: PreTrainedTokenizerBase
+ padding: Union[bool, str, PaddingStrategy] = True
+ max_length: Optional[int] = None
+ pad_to_multiple_of: Optional[int] = None
+
+ def __call__(self, features):
+ label_name = "label" if "label" in features[0].keys() else "labels"
+ labels = [feature.pop(label_name) for feature in features]
+ batch_size = len(features)
+ num_choices = len(features[0]["input_ids"])
+ flattened_features = [
+ [{k: v[i] for k, v in feature.items()} for i in range(num_choices)] for feature in features
+ ]
+ flattened_features = list(chain(*flattened_features))
+
+ batch = self.tokenizer.pad(
+ flattened_features,
+ padding=self.padding,
+ max_length=self.max_length,
+ pad_to_multiple_of=self.pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ # Un-flatten
+ batch = {k: v.view(batch_size, num_choices, -1) for k, v in batch.items()}
+ # Add back labels
+ batch["labels"] = torch.tensor(labels, dtype=torch.int64)
+ return batch
+
+
+def main():
+ args = parse_args()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_swag_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+ accelerator_log_kwargs = {}
+
+ if args.with_tracking:
+ accelerator_log_kwargs["log_with"] = args.report_to
+ accelerator_log_kwargs["project_dir"] = args.output_dir
+
+ accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
+ )
+ else:
+ data_files = {}
+ if args.train_file is not None:
+ data_files["train"] = args.train_file
+ extension = args.train_file.split(".")[-1]
+ if args.validation_file is not None:
+ data_files["validation"] = args.validation_file
+ extension = args.validation_file.split(".")[-1]
+ raw_datasets = load_dataset(extension, data_files=data_files)
+ # Trim a number of training examples
+ if args.debug:
+ for split in raw_datasets.keys():
+ raw_datasets[split] = raw_datasets[split].select(range(100))
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ if raw_datasets["train"] is not None:
+ column_names = raw_datasets["train"].column_names
+ else:
+ column_names = raw_datasets["validation"].column_names
+
+ # When using your own dataset or a different dataset from swag, you will probably need to change this.
+ ending_names = [f"ending{i}" for i in range(4)]
+ context_name = "sent1"
+ question_header_name = "sent2"
+ label_column_name = "label" if "label" in column_names else "labels"
+
+ # Load pretrained model and tokenizer
+ #
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ if args.config_name:
+ config = AutoConfig.from_pretrained(args.model_name_or_path, trust_remote_code=args.trust_remote_code)
+ elif args.model_name_or_path:
+ config = AutoConfig.from_pretrained(args.model_name_or_path, trust_remote_code=args.trust_remote_code)
+ else:
+ config = CONFIG_MAPPING[args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ if args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.tokenizer_name, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
+ )
+ elif args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.model_name_or_path, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
+ )
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if args.model_name_or_path:
+ model = AutoModelForMultipleChoice.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ trust_remote_code=args.trust_remote_code,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = AutoModelForMultipleChoice.from_config(config, trust_remote_code=args.trust_remote_code)
+
+ # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
+ # on a small vocab and want a smaller embedding size, remove this test.
+ embedding_size = model.get_input_embeddings().weight.shape[0]
+ if len(tokenizer) > embedding_size:
+ model.resize_token_embeddings(len(tokenizer))
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ padding = "max_length" if args.pad_to_max_length else False
+
+ def preprocess_function(examples):
+ first_sentences = [[context] * 4 for context in examples[context_name]]
+ question_headers = examples[question_header_name]
+ second_sentences = [
+ [f"{header} {examples[end][i]}" for end in ending_names] for i, header in enumerate(question_headers)
+ ]
+ labels = examples[label_column_name]
+
+ # Flatten out
+ first_sentences = list(chain(*first_sentences))
+ second_sentences = list(chain(*second_sentences))
+
+ # Tokenize
+ tokenized_examples = tokenizer(
+ first_sentences,
+ second_sentences,
+ max_length=args.max_seq_length,
+ padding=padding,
+ truncation=True,
+ )
+ # Un-flatten
+ tokenized_inputs = {k: [v[i : i + 4] for i in range(0, len(v), 4)] for k, v in tokenized_examples.items()}
+ tokenized_inputs["labels"] = labels
+ return tokenized_inputs
+
+ with accelerator.main_process_first():
+ processed_datasets = raw_datasets.map(
+ preprocess_function, batched=True, remove_columns=raw_datasets["train"].column_names
+ )
+
+ train_dataset = processed_datasets["train"]
+ eval_dataset = processed_datasets["validation"]
+
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ # DataLoaders creation:
+ if args.pad_to_max_length:
+ # If padding was already done ot max length, we use the default data collator that will just convert everything
+ # to tensors.
+ data_collator = default_data_collator
+ else:
+ # Otherwise, `DataCollatorWithPadding` will apply dynamic padding for us (by padding to the maximum length of
+ # the samples passed). When using mixed precision, we add `pad_to_multiple_of=8` to pad all tensors to multiple
+ # of 8s, which will enable the use of Tensor Cores on NVIDIA hardware with compute capability >= 7.5 (Volta).
+ # For fp8, we pad to multiple of 16.
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+ data_collator = DataCollatorForMultipleChoice(tokenizer, pad_to_multiple_of=pad_to_multiple_of)
+
+ train_dataloader = DataLoader(
+ train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
+ )
+ eval_dataloader = DataLoader(eval_dataset, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size)
+
+ # Optimizer
+ # Split weights in two groups, one with weight decay and the other not.
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
+
+ # Use the device given by the `accelerator` object.
+ device = accelerator.device
+ model.to(device)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
+ num_training_steps=args.max_train_steps
+ if overrode_max_train_steps
+ else args.max_train_steps * accelerator.num_processes,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("swag_no_trainer", experiment_config)
+
+ # Metrics
+ metric = evaluate.load("accuracy")
+
+ # Train!
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ checkpoint_path = args.resume_from_checkpoint
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ checkpoint_path = path
+ path = os.path.basename(checkpoint_path)
+
+ accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
+ accelerator.load_state(checkpoint_path)
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ completed_steps = resume_step // args.gradient_accumulation_steps
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We skip the first `n` batches in the dataloader when resuming from a checkpoint
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ with accelerator.accumulate(model):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # Checks if the accelerator has performed an optimization step behind the scenes
+ if accelerator.sync_gradients:
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if completed_steps >= args.max_train_steps:
+ break
+
+ model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ accelerator.print(f"epoch {epoch}: {eval_metric}")
+
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "accuracy": eval_metric,
+ "train_loss": total_loss.item() / len(train_dataloader),
+ "epoch": epoch,
+ "step": completed_steps,
+ },
+ step=completed_steps,
+ )
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if args.checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.with_tracking:
+ accelerator.end_training()
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ if args.push_to_hub:
+ api.upload_folder(
+ commit_message="End of training",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+ all_results = {f"eval_{k}": v for k, v in eval_metric.items()}
+ with open(os.path.join(args.output_dir, "all_results.json"), "w") as f:
+ json.dump(all_results, f)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/object-detection/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/object-detection/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..ab474f76075305076a8c28ed02213d83f100b973
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/object-detection/README.md
@@ -0,0 +1,233 @@
+
+
+# Object detection examples
+
+This directory contains 2 scripts that showcase how to fine-tune any model supported by the [`AutoModelForObjectDetection` API](https://huggingface.co/docs/transformers/main/en/model_doc/auto#transformers.AutoModelForObjectDetection) (such as [DETR](https://huggingface.co/docs/transformers/main/en/model_doc/detr), [DETA](https://huggingface.co/docs/transformers/main/en/model_doc/deta), [Deformable DETR](https://huggingface.co/docs/transformers/main/en/model_doc/deformable_detr)) using PyTorch.
+
+Content:
+* [PyTorch version, Trainer](#pytorch-version-trainer)
+* [PyTorch version, no Trainer](#pytorch-version-no-trainer)
+* [Reload and perform inference](#reload-and-perform-inference)
+* [Note on custom data](#note-on-custom-data)
+
+
+## PyTorch version, Trainer
+
+Based on the script [`run_object_detection.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/object-detection/run_object_detection.py).
+
+The script leverages the [🤗 Trainer API](https://huggingface.co/docs/transformers/main_classes/trainer) to automatically take care of the training for you, running on distributed environments right away.
+
+Here we show how to fine-tune a [DETR](https://huggingface.co/facebook/detr-resnet-50) model on the [CPPE-5](https://huggingface.co/datasets/cppe-5) dataset:
+
+```bash
+python run_object_detection.py \
+ --model_name_or_path facebook/detr-resnet-50 \
+ --dataset_name cppe-5 \
+ --do_train true \
+ --do_eval true \
+ --output_dir detr-finetuned-cppe-5-10k-steps \
+ --num_train_epochs 100 \
+ --image_square_size 600 \
+ --fp16 true \
+ --learning_rate 5e-5 \
+ --weight_decay 1e-4 \
+ --dataloader_num_workers 4 \
+ --dataloader_prefetch_factor 2 \
+ --per_device_train_batch_size 8 \
+ --gradient_accumulation_steps 1 \
+ --remove_unused_columns false \
+ --eval_do_concat_batches false \
+ --ignore_mismatched_sizes true \
+ --metric_for_best_model eval_map \
+ --greater_is_better true \
+ --load_best_model_at_end true \
+ --logging_strategy epoch \
+ --evaluation_strategy epoch \
+ --save_strategy epoch \
+ --save_total_limit 2 \
+ --push_to_hub true \
+ --push_to_hub_model_id detr-finetuned-cppe-5-10k-steps \
+ --hub_strategy end \
+ --seed 1337
+```
+
+> Note:
+`--eval_do_concat_batches false` is required for correct evaluation of detection models;
+`--ignore_mismatched_sizes true` is required to load detection model for finetuning with different number of classes.
+
+The resulting model can be seen here: https://huggingface.co/qubvel-hf/qubvel-hf/detr-resnet-50-finetuned-10k-cppe5. The corresponding Weights and Biases report [here](https://api.wandb.ai/links/qubvel-hf-co/bnm0r5ex). Note that it's always advised to check the original paper to know the details regarding training hyperparameters. Hyperparameters for current example were not tuned. To improve model quality you could try:
+ - changing image size parameters (`--shortest_edge`/`--longest_edge`)
+ - changing training parameters, such as learning rate, batch size, warmup, optimizer and many more (see [TrainingArguments](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments))
+ - adding more image augmentations (we created a helpful [HF Space](https://huggingface.co/spaces/qubvel-hf/albumentations-demo) to choose some)
+
+Note that you can replace the model and dataset by simply setting the `model_name_or_path` and `dataset_name` arguments respectively, with model or dataset from the [hub](https://huggingface.co/).
+For dataset, make sure it provides labels in the same format as [CPPE-5](https://huggingface.co/datasets/cppe-5) dataset and boxes are provided in [COCO format](https://albumentations.ai/docs/getting_started/bounding_boxes_augmentation/#coco).
+
+
+
+
+## PyTorch version, no Trainer
+
+Based on the script [`run_object_detection_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/object-detection/run_object_detection.py).
+
+The script leverages [🤗 `Accelerate`](https://github.com/huggingface/accelerate), which allows to write your own training loop in PyTorch, but have it run instantly on any (distributed) environment, including CPU, multi-CPU, GPU, multi-GPU and TPU. It also supports mixed precision.
+
+First, run:
+
+```bash
+accelerate config
+```
+
+and reply to the questions asked regarding the environment on which you'd like to train. Then
+
+```bash
+accelerate test
+```
+
+that will check everything is ready for training. Finally, you can launch training with
+
+```bash
+accelerate launch run_object_detection_no_trainer.py \
+ --model_name_or_path "facebook/detr-resnet-50" \
+ --dataset_name cppe-5 \
+ --output_dir "detr-resnet-50-finetuned" \
+ --num_train_epochs 100 \
+ --image_square_size 600 \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 8 \
+ --checkpointing_steps epoch \
+ --learning_rate 5e-5 \
+ --ignore_mismatched_sizes \
+ --with_tracking \
+ --push_to_hub
+```
+
+and boom, you're training, possibly on multiple GPUs, logging everything to all trackers found in your environment (like Weights and Biases, Tensorboard) and regularly pushing your model to the hub (with the repo name being equal to `args.output_dir` at your HF username) 🤗
+
+With the default settings, the script fine-tunes a [DETR](https://huggingface.co/facebook/detr-resnet-50) model on the [CPPE-5](https://huggingface.co/datasets/cppe-5) dataset. The resulting model can be seen here: https://huggingface.co/qubvel-hf/detr-resnet-50-finetuned-10k-cppe5-no-trainer.
+
+
+## Reload and perform inference
+
+This means that after training, you can easily load your trained model and perform inference as follows::
+
+```python
+import requests
+import torch
+
+from PIL import Image
+from transformers import AutoImageProcessor, AutoModelForObjectDetection
+
+# Name of repo on the hub or path to a local folder
+model_name = "qubvel-hf/detr-resnet-50-finetuned-10k-cppe5"
+
+image_processor = AutoImageProcessor.from_pretrained(model_name)
+model = AutoModelForObjectDetection.from_pretrained(model_name)
+
+# Load image for inference
+url = "https://images.pexels.com/photos/8413299/pexels-photo-8413299.jpeg?auto=compress&cs=tinysrgb&w=630&h=375&dpr=2"
+image = Image.open(requests.get(url, stream=True).raw)
+
+# Prepare image for the model
+inputs = image_processor(images=image, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+# Post process model predictions
+# this include conversion to Pascal VOC format and filtering non confident boxes
+width, height = image.size
+target_sizes = torch.tensor([height, width]).unsqueeze(0) # add batch dim
+results = image_processor.post_process_object_detection(outputs, threshold=0.5, target_sizes=target_sizes)[0]
+
+for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
+ box = [round(i, 2) for i in box.tolist()]
+ print(
+ f"Detected {model.config.id2label[label.item()]} with confidence "
+ f"{round(score.item(), 3)} at location {box}"
+ )
+```
+
+And visualize with the following code:
+```python
+from PIL import ImageDraw
+draw = ImageDraw.Draw(image)
+
+for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
+ box = [round(i, 2) for i in box.tolist()]
+ x, y, x2, y2 = tuple(box)
+ draw.rectangle((x, y, x2, y2), outline="red", width=1)
+ draw.text((x, y), model.config.id2label[label.item()], fill="white")
+
+image
+```
+
+
+## Note on custom data
+
+In case you'd like to use the script with custom data, you could prepare your data with the following way:
+
+```bash
+custom_dataset/
+└── train
+ ├── 0001.jpg
+ ├── 0002.jpg
+ ├── ...
+ └── metadata.jsonl
+└── validation
+ └── ...
+└── test
+ └── ...
+```
+
+Where `metadata.jsonl` is a file with the following structure:
+```json
+{"file_name": "0001.jpg", "objects": {"bbox": [[302.0, 109.0, 73.0, 52.0]], "categories": [0], "id": [1], "area": [50.0]}}
+{"file_name": "0002.jpg", "objects": {"bbox": [[810.0, 100.0, 57.0, 28.0]], "categories": [1], "id": [2], "area": [40.0]}}
+...
+```
+Trining script support bounding boxes in COCO format (x_min, y_min, width, height).
+
+Then, you cat load the dataset with just a few lines of code:
+
+```python
+from datasets import load_dataset
+
+# Load dataset
+dataset = load_dataset("imagefolder", data_dir="custom_dataset/")
+
+# >>> DatasetDict({
+# ... train: Dataset({
+# ... features: ['image', 'objects'],
+# ... num_rows: 2
+# ... })
+# ... })
+
+# Push to hub (assumes you have ran the huggingface-cli login command in a terminal/notebook)
+dataset.push_to_hub("name of repo on the hub")
+
+# optionally, you can push to a private repo on the hub
+# dataset.push_to_hub("name of repo on the hub", private=True)
+```
+
+And the final step, for training you should provide id2label mapping in the following way:
+```python
+id2label = {0: "Car", 1: "Bird", ...}
+```
+Just find it in code and replace for simplicity, or save `json` locally and with the dataset on the hub!
+
+See also: [Dataset Creation Guide](https://huggingface.co/docs/datasets/image_dataset#create-an-image-dataset)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/object-detection/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/object-detection/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..7772958dee7af88f31167f8fe2fb5af4fb1e1866
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/object-detection/requirements.txt
@@ -0,0 +1,5 @@
+albumentations >= 1.4.16
+timm
+datasets
+torchmetrics
+pycocotools
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/object-detection/run_object_detection.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/object-detection/run_object_detection.py
new file mode 100644
index 0000000000000000000000000000000000000000..8d722f4d5d5ddb57cdb45ad6bf2e67b833fad854
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/object-detection/run_object_detection.py
@@ -0,0 +1,523 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+
+"""Finetuning any 🤗 Transformers model supported by AutoModelForObjectDetection for object detection leveraging the Trainer API."""
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from functools import partial
+from typing import Any, List, Mapping, Optional, Tuple, Union
+
+import albumentations as A
+import numpy as np
+import torch
+from datasets import load_dataset
+from torchmetrics.detection.mean_ap import MeanAveragePrecision
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoImageProcessor,
+ AutoModelForObjectDetection,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+)
+from transformers.image_processing_utils import BatchFeature
+from transformers.image_transforms import center_to_corners_format
+from transformers.trainer import EvalPrediction
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+logger = logging.getLogger(__name__)
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=2.0.0", "To fix: pip install -r examples/pytorch/object-detection/requirements.txt")
+
+
+@dataclass
+class ModelOutput:
+ logits: torch.Tensor
+ pred_boxes: torch.Tensor
+
+
+def format_image_annotations_as_coco(
+ image_id: str, categories: List[int], areas: List[float], bboxes: List[Tuple[float]]
+) -> dict:
+ """Format one set of image annotations to the COCO format
+
+ Args:
+ image_id (str): image id. e.g. "0001"
+ categories (List[int]): list of categories/class labels corresponding to provided bounding boxes
+ areas (List[float]): list of corresponding areas to provided bounding boxes
+ bboxes (List[Tuple[float]]): list of bounding boxes provided in COCO format
+ ([center_x, center_y, width, height] in absolute coordinates)
+
+ Returns:
+ dict: {
+ "image_id": image id,
+ "annotations": list of formatted annotations
+ }
+ """
+ annotations = []
+ for category, area, bbox in zip(categories, areas, bboxes):
+ formatted_annotation = {
+ "image_id": image_id,
+ "category_id": category,
+ "iscrowd": 0,
+ "area": area,
+ "bbox": list(bbox),
+ }
+ annotations.append(formatted_annotation)
+
+ return {
+ "image_id": image_id,
+ "annotations": annotations,
+ }
+
+
+def convert_bbox_yolo_to_pascal(boxes: torch.Tensor, image_size: Tuple[int, int]) -> torch.Tensor:
+ """
+ Convert bounding boxes from YOLO format (x_center, y_center, width, height) in range [0, 1]
+ to Pascal VOC format (x_min, y_min, x_max, y_max) in absolute coordinates.
+
+ Args:
+ boxes (torch.Tensor): Bounding boxes in YOLO format
+ image_size (Tuple[int, int]): Image size in format (height, width)
+
+ Returns:
+ torch.Tensor: Bounding boxes in Pascal VOC format (x_min, y_min, x_max, y_max)
+ """
+ # convert center to corners format
+ boxes = center_to_corners_format(boxes)
+
+ # convert to absolute coordinates
+ height, width = image_size
+ boxes = boxes * torch.tensor([[width, height, width, height]])
+
+ return boxes
+
+
+def augment_and_transform_batch(
+ examples: Mapping[str, Any],
+ transform: A.Compose,
+ image_processor: AutoImageProcessor,
+ return_pixel_mask: bool = False,
+) -> BatchFeature:
+ """Apply augmentations and format annotations in COCO format for object detection task"""
+
+ images = []
+ annotations = []
+ for image_id, image, objects in zip(examples["image_id"], examples["image"], examples["objects"]):
+ image = np.array(image.convert("RGB"))
+
+ # apply augmentations
+ output = transform(image=image, bboxes=objects["bbox"], category=objects["category"])
+ images.append(output["image"])
+
+ # format annotations in COCO format
+ formatted_annotations = format_image_annotations_as_coco(
+ image_id, output["category"], objects["area"], output["bboxes"]
+ )
+ annotations.append(formatted_annotations)
+
+ # Apply the image processor transformations: resizing, rescaling, normalization
+ result = image_processor(images=images, annotations=annotations, return_tensors="pt")
+
+ if not return_pixel_mask:
+ result.pop("pixel_mask", None)
+
+ return result
+
+
+def collate_fn(batch: List[BatchFeature]) -> Mapping[str, Union[torch.Tensor, List[Any]]]:
+ data = {}
+ data["pixel_values"] = torch.stack([x["pixel_values"] for x in batch])
+ data["labels"] = [x["labels"] for x in batch]
+ if "pixel_mask" in batch[0]:
+ data["pixel_mask"] = torch.stack([x["pixel_mask"] for x in batch])
+ return data
+
+
+@torch.no_grad()
+def compute_metrics(
+ evaluation_results: EvalPrediction,
+ image_processor: AutoImageProcessor,
+ threshold: float = 0.0,
+ id2label: Optional[Mapping[int, str]] = None,
+) -> Mapping[str, float]:
+ """
+ Compute mean average mAP, mAR and their variants for the object detection task.
+
+ Args:
+ evaluation_results (EvalPrediction): Predictions and targets from evaluation.
+ threshold (float, optional): Threshold to filter predicted boxes by confidence. Defaults to 0.0.
+ id2label (Optional[dict], optional): Mapping from class id to class name. Defaults to None.
+
+ Returns:
+ Mapping[str, float]: Metrics in a form of dictionary {: }
+ """
+
+ predictions, targets = evaluation_results.predictions, evaluation_results.label_ids
+
+ # For metric computation we need to provide:
+ # - targets in a form of list of dictionaries with keys "boxes", "labels"
+ # - predictions in a form of list of dictionaries with keys "boxes", "scores", "labels"
+
+ image_sizes = []
+ post_processed_targets = []
+ post_processed_predictions = []
+
+ # Collect targets in the required format for metric computation
+ for batch in targets:
+ # collect image sizes, we will need them for predictions post processing
+ batch_image_sizes = torch.tensor([x["orig_size"] for x in batch])
+ image_sizes.append(batch_image_sizes)
+ # collect targets in the required format for metric computation
+ # boxes were converted to YOLO format needed for model training
+ # here we will convert them to Pascal VOC format (x_min, y_min, x_max, y_max)
+ for image_target in batch:
+ boxes = torch.tensor(image_target["boxes"])
+ boxes = convert_bbox_yolo_to_pascal(boxes, image_target["orig_size"])
+ labels = torch.tensor(image_target["class_labels"])
+ post_processed_targets.append({"boxes": boxes, "labels": labels})
+
+ # Collect predictions in the required format for metric computation,
+ # model produce boxes in YOLO format, then image_processor convert them to Pascal VOC format
+ for batch, target_sizes in zip(predictions, image_sizes):
+ batch_logits, batch_boxes = batch[1], batch[2]
+ output = ModelOutput(logits=torch.tensor(batch_logits), pred_boxes=torch.tensor(batch_boxes))
+ post_processed_output = image_processor.post_process_object_detection(
+ output, threshold=threshold, target_sizes=target_sizes
+ )
+ post_processed_predictions.extend(post_processed_output)
+
+ # Compute metrics
+ metric = MeanAveragePrecision(box_format="xyxy", class_metrics=True)
+ metric.update(post_processed_predictions, post_processed_targets)
+ metrics = metric.compute()
+
+ # Replace list of per class metrics with separate metric for each class
+ classes = metrics.pop("classes")
+ map_per_class = metrics.pop("map_per_class")
+ mar_100_per_class = metrics.pop("mar_100_per_class")
+ for class_id, class_map, class_mar in zip(classes, map_per_class, mar_100_per_class):
+ class_name = id2label[class_id.item()] if id2label is not None else class_id.item()
+ metrics[f"map_{class_name}"] = class_map
+ metrics[f"mar_100_{class_name}"] = class_mar
+
+ metrics = {k: round(v.item(), 4) for k, v in metrics.items()}
+
+ return metrics
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ Using `HfArgumentParser` we can turn this class into argparse arguments to be able to specify
+ them on the command line.
+ """
+
+ dataset_name: str = field(
+ default="cppe-5",
+ metadata={
+ "help": "Name of a dataset from the hub (could be your own, possibly private dataset hosted on the hub)."
+ },
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_val_split: Optional[float] = field(
+ default=0.15, metadata={"help": "Percent to split off of train for validation."}
+ )
+ image_square_size: Optional[int] = field(
+ default=600,
+ metadata={"help": "Image longest size will be resized to this value, then image will be padded to square."},
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ default="facebook/detr-resnet-50",
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"},
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ image_processor_name: str = field(default=None, metadata={"help": "Name or path of preprocessor config."})
+ ignore_mismatched_sizes: bool = field(
+ default=False,
+ metadata={
+ "help": "Whether or not to raise an error if some of the weights from the checkpoint do not have the same size as the weights of the model (if for instance, you are instantiating a model with 10 labels from a checkpoint with 3 labels)."
+ },
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_object_detection", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif os.path.isdir(training_args.output_dir) and not training_args.overwrite_output_dir:
+ checkpoint = get_last_checkpoint(training_args.output_dir)
+ if checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # ------------------------------------------------------------------------------------------------
+ # Load dataset, prepare splits
+ # ------------------------------------------------------------------------------------------------
+
+ dataset = load_dataset(
+ data_args.dataset_name, cache_dir=model_args.cache_dir, trust_remote_code=model_args.trust_remote_code
+ )
+
+ # If we don't have a validation split, split off a percentage of train as validation
+ data_args.train_val_split = None if "validation" in dataset.keys() else data_args.train_val_split
+ if isinstance(data_args.train_val_split, float) and data_args.train_val_split > 0.0:
+ split = dataset["train"].train_test_split(data_args.train_val_split, seed=training_args.seed)
+ dataset["train"] = split["train"]
+ dataset["validation"] = split["test"]
+
+ # Get dataset categories and prepare mappings for label_name <-> label_id
+ categories = dataset["train"].features["objects"].feature["category"].names
+ id2label = dict(enumerate(categories))
+ label2id = {v: k for k, v in id2label.items()}
+
+ # ------------------------------------------------------------------------------------------------
+ # Load pretrained config, model and image processor
+ # ------------------------------------------------------------------------------------------------
+
+ common_pretrained_args = {
+ "cache_dir": model_args.cache_dir,
+ "revision": model_args.model_revision,
+ "token": model_args.token,
+ "trust_remote_code": model_args.trust_remote_code,
+ }
+ config = AutoConfig.from_pretrained(
+ model_args.config_name or model_args.model_name_or_path,
+ label2id=label2id,
+ id2label=id2label,
+ **common_pretrained_args,
+ )
+ model = AutoModelForObjectDetection.from_pretrained(
+ model_args.model_name_or_path,
+ config=config,
+ ignore_mismatched_sizes=model_args.ignore_mismatched_sizes,
+ **common_pretrained_args,
+ )
+ image_processor = AutoImageProcessor.from_pretrained(
+ model_args.image_processor_name or model_args.model_name_or_path,
+ do_resize=True,
+ size={"max_height": data_args.image_square_size, "max_width": data_args.image_square_size},
+ do_pad=True,
+ pad_size={"height": data_args.image_square_size, "width": data_args.image_square_size},
+ **common_pretrained_args,
+ )
+
+ # ------------------------------------------------------------------------------------------------
+ # Define image augmentations and dataset transforms
+ # ------------------------------------------------------------------------------------------------
+ max_size = data_args.image_square_size
+ train_augment_and_transform = A.Compose(
+ [
+ A.Compose(
+ [
+ A.SmallestMaxSize(max_size=max_size, p=1.0),
+ A.RandomSizedBBoxSafeCrop(height=max_size, width=max_size, p=1.0),
+ ],
+ p=0.2,
+ ),
+ A.OneOf(
+ [
+ A.Blur(blur_limit=7, p=0.5),
+ A.MotionBlur(blur_limit=7, p=0.5),
+ A.Defocus(radius=(1, 5), alias_blur=(0.1, 0.25), p=0.1),
+ ],
+ p=0.1,
+ ),
+ A.Perspective(p=0.1),
+ A.HorizontalFlip(p=0.5),
+ A.RandomBrightnessContrast(p=0.5),
+ A.HueSaturationValue(p=0.1),
+ ],
+ bbox_params=A.BboxParams(format="coco", label_fields=["category"], clip=True, min_area=25),
+ )
+ validation_transform = A.Compose(
+ [A.NoOp()],
+ bbox_params=A.BboxParams(format="coco", label_fields=["category"], clip=True),
+ )
+
+ # Make transform functions for batch and apply for dataset splits
+ train_transform_batch = partial(
+ augment_and_transform_batch, transform=train_augment_and_transform, image_processor=image_processor
+ )
+ validation_transform_batch = partial(
+ augment_and_transform_batch, transform=validation_transform, image_processor=image_processor
+ )
+
+ dataset["train"] = dataset["train"].with_transform(train_transform_batch)
+ dataset["validation"] = dataset["validation"].with_transform(validation_transform_batch)
+ dataset["test"] = dataset["test"].with_transform(validation_transform_batch)
+
+ # ------------------------------------------------------------------------------------------------
+ # Model training and evaluation with Trainer API
+ # ------------------------------------------------------------------------------------------------
+
+ eval_compute_metrics_fn = partial(
+ compute_metrics, image_processor=image_processor, id2label=id2label, threshold=0.0
+ )
+
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=dataset["train"] if training_args.do_train else None,
+ eval_dataset=dataset["validation"] if training_args.do_eval else None,
+ processing_class=image_processor,
+ data_collator=collate_fn,
+ compute_metrics=eval_compute_metrics_fn,
+ )
+
+ # Training
+ if training_args.do_train:
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model()
+ trainer.log_metrics("train", train_result.metrics)
+ trainer.save_metrics("train", train_result.metrics)
+ trainer.save_state()
+
+ # Final evaluation
+ if training_args.do_eval:
+ metrics = trainer.evaluate(eval_dataset=dataset["test"], metric_key_prefix="test")
+ trainer.log_metrics("test", metrics)
+ trainer.save_metrics("test", metrics)
+
+ # Write model card and (optionally) push to hub
+ kwargs = {
+ "finetuned_from": model_args.model_name_or_path,
+ "dataset": data_args.dataset_name,
+ "tags": ["object-detection", "vision"],
+ }
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/object-detection/run_object_detection_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/object-detection/run_object_detection_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..dbfcb3fd97fae83ba5c92639a2c2b4eaa4dcbcfd
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/object-detection/run_object_detection_no_trainer.py
@@ -0,0 +1,782 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Finetuning 🤗 Transformers model for object detection with Accelerate."""
+
+import argparse
+import json
+import logging
+import math
+import os
+from functools import partial
+from pathlib import Path
+from typing import Any, List, Mapping, Tuple, Union
+
+import albumentations as A
+import datasets
+import numpy as np
+import torch
+from accelerate import Accelerator
+from accelerate.logging import get_logger
+from accelerate.utils import set_seed
+from datasets import load_dataset
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from torchmetrics.detection.mean_ap import MeanAveragePrecision
+from tqdm.auto import tqdm
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoImageProcessor,
+ AutoModelForObjectDetection,
+ SchedulerType,
+ get_scheduler,
+)
+from transformers.image_processing_utils import BatchFeature
+from transformers.image_transforms import center_to_corners_format
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+logging.basicConfig(level=logging.INFO)
+logger = get_logger(__name__)
+
+require_version("datasets>=2.0.0", "To fix: pip install -r examples/pytorch/semantic-segmentation/requirements.txt")
+
+
+# Copied from examples/pytorch/object-detection/run_object_detection.format_image_annotations_as_coco
+def format_image_annotations_as_coco(
+ image_id: str, categories: List[int], areas: List[float], bboxes: List[Tuple[float]]
+) -> dict:
+ """Format one set of image annotations to the COCO format
+
+ Args:
+ image_id (str): image id. e.g. "0001"
+ categories (List[int]): list of categories/class labels corresponding to provided bounding boxes
+ areas (List[float]): list of corresponding areas to provided bounding boxes
+ bboxes (List[Tuple[float]]): list of bounding boxes provided in COCO format
+ ([center_x, center_y, width, height] in absolute coordinates)
+
+ Returns:
+ dict: {
+ "image_id": image id,
+ "annotations": list of formatted annotations
+ }
+ """
+ annotations = []
+ for category, area, bbox in zip(categories, areas, bboxes):
+ formatted_annotation = {
+ "image_id": image_id,
+ "category_id": category,
+ "iscrowd": 0,
+ "area": area,
+ "bbox": list(bbox),
+ }
+ annotations.append(formatted_annotation)
+
+ return {
+ "image_id": image_id,
+ "annotations": annotations,
+ }
+
+
+# Copied from examples/pytorch/object-detection/run_object_detection.convert_bbox_yolo_to_pascal
+def convert_bbox_yolo_to_pascal(boxes: torch.Tensor, image_size: Tuple[int, int]) -> torch.Tensor:
+ """
+ Convert bounding boxes from YOLO format (x_center, y_center, width, height) in range [0, 1]
+ to Pascal VOC format (x_min, y_min, x_max, y_max) in absolute coordinates.
+
+ Args:
+ boxes (torch.Tensor): Bounding boxes in YOLO format
+ image_size (Tuple[int, int]): Image size in format (height, width)
+
+ Returns:
+ torch.Tensor: Bounding boxes in Pascal VOC format (x_min, y_min, x_max, y_max)
+ """
+ # convert center to corners format
+ boxes = center_to_corners_format(boxes)
+
+ # convert to absolute coordinates
+ height, width = image_size
+ boxes = boxes * torch.tensor([[width, height, width, height]])
+
+ return boxes
+
+
+# Copied from examples/pytorch/object-detection/run_object_detection.augment_and_transform_batch
+def augment_and_transform_batch(
+ examples: Mapping[str, Any],
+ transform: A.Compose,
+ image_processor: AutoImageProcessor,
+ return_pixel_mask: bool = False,
+) -> BatchFeature:
+ """Apply augmentations and format annotations in COCO format for object detection task"""
+
+ images = []
+ annotations = []
+ for image_id, image, objects in zip(examples["image_id"], examples["image"], examples["objects"]):
+ image = np.array(image.convert("RGB"))
+
+ # apply augmentations
+ output = transform(image=image, bboxes=objects["bbox"], category=objects["category"])
+ images.append(output["image"])
+
+ # format annotations in COCO format
+ formatted_annotations = format_image_annotations_as_coco(
+ image_id, output["category"], objects["area"], output["bboxes"]
+ )
+ annotations.append(formatted_annotations)
+
+ # Apply the image processor transformations: resizing, rescaling, normalization
+ result = image_processor(images=images, annotations=annotations, return_tensors="pt")
+
+ if not return_pixel_mask:
+ result.pop("pixel_mask", None)
+
+ return result
+
+
+# Copied from examples/pytorch/object-detection/run_object_detection.collate_fn
+def collate_fn(batch: List[BatchFeature]) -> Mapping[str, Union[torch.Tensor, List[Any]]]:
+ data = {}
+ data["pixel_values"] = torch.stack([x["pixel_values"] for x in batch])
+ data["labels"] = [x["labels"] for x in batch]
+ if "pixel_mask" in batch[0]:
+ data["pixel_mask"] = torch.stack([x["pixel_mask"] for x in batch])
+ return data
+
+
+def nested_to_cpu(objects):
+ """Move nested tesnors in objects to CPU if they are on GPU"""
+ if isinstance(objects, torch.Tensor):
+ return objects.cpu()
+ elif isinstance(objects, Mapping):
+ return type(objects)({k: nested_to_cpu(v) for k, v in objects.items()})
+ elif isinstance(objects, (list, tuple)):
+ return type(objects)([nested_to_cpu(v) for v in objects])
+ elif isinstance(objects, (np.ndarray, str, int, float, bool)):
+ return objects
+ raise ValueError(f"Unsupported type {type(objects)}")
+
+
+def evaluation_loop(
+ model: torch.nn.Module,
+ image_processor: AutoImageProcessor,
+ accelerator: Accelerator,
+ dataloader: DataLoader,
+ id2label: Mapping[int, str],
+) -> dict:
+ model.eval()
+ metric = MeanAveragePrecision(box_format="xyxy", class_metrics=True)
+
+ for step, batch in enumerate(tqdm(dataloader, disable=not accelerator.is_local_main_process)):
+ with torch.no_grad():
+ outputs = model(**batch)
+
+ # For metric computation we need to collect ground truth and predicted boxes in the same format
+
+ # 1. Collect predicted boxes, classes, scores
+ # image_processor convert boxes from YOLO format to Pascal VOC format
+ # ([x_min, y_min, x_max, y_max] in absolute coordinates)
+ image_size = torch.stack([example["orig_size"] for example in batch["labels"]], dim=0)
+ predictions = image_processor.post_process_object_detection(outputs, threshold=0.0, target_sizes=image_size)
+ predictions = nested_to_cpu(predictions)
+
+ # 2. Collect ground truth boxes in the same format for metric computation
+ # Do the same, convert YOLO boxes to Pascal VOC format
+ target = []
+ for label in batch["labels"]:
+ label = nested_to_cpu(label)
+ boxes = convert_bbox_yolo_to_pascal(label["boxes"], label["orig_size"])
+ labels = label["class_labels"]
+ target.append({"boxes": boxes, "labels": labels})
+
+ metric.update(predictions, target)
+
+ metrics = metric.compute()
+
+ # Replace list of per class metrics with separate metric for each class
+ classes = metrics.pop("classes")
+ map_per_class = metrics.pop("map_per_class")
+ mar_100_per_class = metrics.pop("mar_100_per_class")
+ for class_id, class_map, class_mar in zip(classes, map_per_class, mar_100_per_class):
+ class_name = id2label[class_id.item()]
+ metrics[f"map_{class_name}"] = class_map
+ metrics[f"mar_100_{class_name}"] = class_mar
+
+ # Convert metrics to float
+ metrics = {k: round(v.item(), 4) for k, v in metrics.items()}
+
+ return metrics
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Finetune a transformers model for object detection task")
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to a pretrained model or model identifier from huggingface.co/models.",
+ default="facebook/detr-resnet-50",
+ )
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ help="Name of the dataset on the hub.",
+ default="cppe-5",
+ )
+ parser.add_argument(
+ "--train_val_split",
+ type=float,
+ default=0.15,
+ help="Fraction of the dataset to be used for validation.",
+ )
+ parser.add_argument(
+ "--ignore_mismatched_sizes",
+ action="store_true",
+ help="Ignore mismatched sizes between the model and the dataset.",
+ )
+ parser.add_argument(
+ "--image_square_size",
+ type=int,
+ default=1333,
+ help="Image longest size will be resized to this value, then image will be padded to square.",
+ )
+ parser.add_argument(
+ "--cache_dir",
+ type=str,
+ help="Path to a folder in which the model and dataset will be cached.",
+ )
+ parser.add_argument(
+ "--use_auth_token",
+ action="store_true",
+ help="Whether to use an authentication token to access the model repository.",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--dataloader_num_workers",
+ type=int,
+ default=4,
+ help="Number of workers to use for the dataloaders.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument(
+ "--adam_beta1",
+ type=float,
+ default=0.9,
+ help="Beta1 for AdamW optimizer",
+ )
+ parser.add_argument(
+ "--adam_beta2",
+ type=float,
+ default=0.999,
+ help="Beta2 for AdamW optimizer",
+ )
+ parser.add_argument(
+ "--adam_epsilon",
+ type=float,
+ default=1e-8,
+ help="Epsilon for AdamW optimizer",
+ )
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--trust_remote_code",
+ action="store_true",
+ help=(
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ required=False,
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+ if args.push_to_hub or args.with_tracking:
+ if args.output_dir is None:
+ raise ValueError(
+ "Need an `output_dir` to create a repo when `--push_to_hub` or `with_tracking` is specified."
+ )
+
+ if args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+
+ return args
+
+
+def main():
+ args = parse_args()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_object_detection_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+ accelerator_log_kwargs = {}
+
+ if args.with_tracking:
+ accelerator_log_kwargs["log_with"] = args.report_to
+ accelerator_log_kwargs["project_dir"] = args.output_dir
+
+ accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
+
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ # We set device_specific to True as we want different data augmentation per device.
+ if args.seed is not None:
+ set_seed(args.seed, device_specific=True)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Load dataset
+ # In distributed training, the load_dataset function guarantees that only one local process can concurrently
+ # download the dataset.
+ dataset = load_dataset(args.dataset_name, cache_dir=args.cache_dir, trust_remote_code=args.trust_remote_code)
+
+ # If we don't have a validation split, split off a percentage of train as validation.
+ args.train_val_split = None if "validation" in dataset.keys() else args.train_val_split
+ if isinstance(args.train_val_split, float) and args.train_val_split > 0.0:
+ split = dataset["train"].train_test_split(args.train_val_split, seed=args.seed)
+ dataset["train"] = split["train"]
+ dataset["validation"] = split["test"]
+
+ # Get dataset categories and prepare mappings for label_name <-> label_id
+ categories = dataset["train"].features["objects"].feature["category"].names
+ id2label = dict(enumerate(categories))
+ label2id = {v: k for k, v in id2label.items()}
+
+ # ------------------------------------------------------------------------------------------------
+ # Load pretrained config, model and image processor
+ # ------------------------------------------------------------------------------------------------
+
+ common_pretrained_args = {
+ "cache_dir": args.cache_dir,
+ "token": args.hub_token,
+ "trust_remote_code": args.trust_remote_code,
+ }
+ config = AutoConfig.from_pretrained(
+ args.model_name_or_path, label2id=label2id, id2label=id2label, **common_pretrained_args
+ )
+ model = AutoModelForObjectDetection.from_pretrained(
+ args.model_name_or_path,
+ config=config,
+ ignore_mismatched_sizes=args.ignore_mismatched_sizes,
+ **common_pretrained_args,
+ )
+ image_processor = AutoImageProcessor.from_pretrained(
+ args.model_name_or_path,
+ do_resize=True,
+ size={"max_height": args.image_square_size, "max_width": args.image_square_size},
+ do_pad=True,
+ pad_size={"height": args.image_square_size, "width": args.image_square_size},
+ **common_pretrained_args,
+ )
+
+ # ------------------------------------------------------------------------------------------------
+ # Define image augmentations and dataset transforms
+ # ------------------------------------------------------------------------------------------------
+ max_size = args.image_square_size
+ train_augment_and_transform = A.Compose(
+ [
+ A.Compose(
+ [
+ A.SmallestMaxSize(max_size=max_size, p=1.0),
+ A.RandomSizedBBoxSafeCrop(height=max_size, width=max_size, p=1.0),
+ ],
+ p=0.2,
+ ),
+ A.OneOf(
+ [
+ A.Blur(blur_limit=7, p=0.5),
+ A.MotionBlur(blur_limit=7, p=0.5),
+ A.Defocus(radius=(1, 5), alias_blur=(0.1, 0.25), p=0.1),
+ ],
+ p=0.1,
+ ),
+ A.Perspective(p=0.1),
+ A.HorizontalFlip(p=0.5),
+ A.RandomBrightnessContrast(p=0.5),
+ A.HueSaturationValue(p=0.1),
+ ],
+ bbox_params=A.BboxParams(format="coco", label_fields=["category"], clip=True, min_area=25),
+ )
+ validation_transform = A.Compose(
+ [A.NoOp()],
+ bbox_params=A.BboxParams(format="coco", label_fields=["category"], clip=True),
+ )
+
+ # Make transform functions for batch and apply for dataset splits
+ train_transform_batch = partial(
+ augment_and_transform_batch, transform=train_augment_and_transform, image_processor=image_processor
+ )
+ validation_transform_batch = partial(
+ augment_and_transform_batch, transform=validation_transform, image_processor=image_processor
+ )
+
+ with accelerator.main_process_first():
+ train_dataset = dataset["train"].with_transform(train_transform_batch)
+ valid_dataset = dataset["validation"].with_transform(validation_transform_batch)
+ test_dataset = dataset["test"].with_transform(validation_transform_batch)
+
+ dataloader_common_args = {
+ "num_workers": args.dataloader_num_workers,
+ "collate_fn": collate_fn,
+ }
+ train_dataloader = DataLoader(
+ train_dataset, shuffle=True, batch_size=args.per_device_train_batch_size, **dataloader_common_args
+ )
+ valid_dataloader = DataLoader(
+ valid_dataset, shuffle=False, batch_size=args.per_device_eval_batch_size, **dataloader_common_args
+ )
+ test_dataloader = DataLoader(
+ test_dataset, shuffle=False, batch_size=args.per_device_eval_batch_size, **dataloader_common_args
+ )
+
+ # ------------------------------------------------------------------------------------------------
+ # Define optimizer, scheduler and prepare everything with the accelerator
+ # ------------------------------------------------------------------------------------------------
+
+ # Optimizer
+ optimizer = torch.optim.AdamW(
+ list(model.parameters()),
+ lr=args.learning_rate,
+ betas=[args.adam_beta1, args.adam_beta2],
+ eps=args.adam_epsilon,
+ )
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
+ num_training_steps=args.max_train_steps
+ if overrode_max_train_steps
+ else args.max_train_steps * accelerator.num_processes,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, valid_dataloader, test_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, valid_dataloader, test_dataloader, lr_scheduler
+ )
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("object_detection_no_trainer", experiment_config)
+
+ # ------------------------------------------------------------------------------------------------
+ # Run training with evaluation on each epoch
+ # ------------------------------------------------------------------------------------------------
+
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ checkpoint_path = args.resume_from_checkpoint
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ checkpoint_path = path
+ path = os.path.basename(checkpoint_path)
+
+ accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
+ accelerator.load_state(checkpoint_path)
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ completed_steps = resume_step // args.gradient_accumulation_steps
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We skip the first `n` batches in the dataloader when resuming from a checkpoint
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+
+ for step, batch in enumerate(active_dataloader):
+ with accelerator.accumulate(model):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # Checks if the accelerator has performed an optimization step behind the scenes
+ if accelerator.sync_gradients:
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir,
+ is_main_process=accelerator.is_main_process,
+ save_function=accelerator.save,
+ )
+ if accelerator.is_main_process:
+ image_processor.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if completed_steps >= args.max_train_steps:
+ break
+
+ logger.info("***** Running evaluation *****")
+ metrics = evaluation_loop(model, image_processor, accelerator, valid_dataloader, id2label)
+
+ logger.info(f"epoch {epoch}: {metrics}")
+
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "train_loss": total_loss.item() / len(train_dataloader),
+ **metrics,
+ "epoch": epoch,
+ "step": completed_steps,
+ },
+ step=completed_steps,
+ )
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ image_processor.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if args.checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ # ------------------------------------------------------------------------------------------------
+ # Run evaluation on test dataset and save the model
+ # ------------------------------------------------------------------------------------------------
+
+ logger.info("***** Running evaluation on test dataset *****")
+ metrics = evaluation_loop(model, image_processor, accelerator, test_dataloader, id2label)
+ metrics = {f"test_{k}": v for k, v in metrics.items()}
+
+ logger.info(f"Test metrics: {metrics}")
+
+ if args.with_tracking:
+ accelerator.end_training()
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ with open(os.path.join(args.output_dir, "all_results.json"), "w") as f:
+ json.dump(metrics, f, indent=2)
+
+ image_processor.save_pretrained(args.output_dir)
+
+ if args.push_to_hub:
+ api.upload_folder(
+ commit_message="End of training",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ ignore_patterns=["epoch_*"],
+ )
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/old_test_xla_examples.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/old_test_xla_examples.py
new file mode 100644
index 0000000000000000000000000000000000000000..c13d8b3115130c01825e98cab97478c4f598e6bd
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/old_test_xla_examples.py
@@ -0,0 +1,94 @@
+# coding=utf-8
+# Copyright 2018 HuggingFace Inc..
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+
+import json
+import logging
+import os
+import sys
+from time import time
+from unittest.mock import patch
+
+from transformers.testing_utils import TestCasePlus, require_torch_xla
+
+
+logging.basicConfig(level=logging.DEBUG)
+
+logger = logging.getLogger()
+
+
+def get_results(output_dir):
+ results = {}
+ path = os.path.join(output_dir, "all_results.json")
+ if os.path.exists(path):
+ with open(path, "r") as f:
+ results = json.load(f)
+ else:
+ raise ValueError(f"can't find {path}")
+ return results
+
+
+stream_handler = logging.StreamHandler(sys.stdout)
+logger.addHandler(stream_handler)
+
+
+@require_torch_xla
+class TorchXLAExamplesTests(TestCasePlus):
+ def test_run_glue(self):
+ import xla_spawn
+
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ ./examples/pytorch/text-classification/run_glue.py
+ --num_cores=8
+ ./examples/pytorch/text-classification/run_glue.py
+ --model_name_or_path distilbert/distilbert-base-uncased
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ --train_file ./tests/fixtures/tests_samples/MRPC/train.csv
+ --validation_file ./tests/fixtures/tests_samples/MRPC/dev.csv
+ --do_train
+ --do_eval
+ --debug tpu_metrics_debug
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --learning_rate=1e-4
+ --max_steps=10
+ --warmup_steps=2
+ --seed=42
+ --max_seq_length=128
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ start = time()
+ xla_spawn.main()
+ end = time()
+
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_accuracy"], 0.75)
+
+ # Assert that the script takes less than 500 seconds to make sure it doesn't hang.
+ self.assertLess(end - start, 500)
+
+ def test_trainer_tpu(self):
+ import xla_spawn
+
+ testargs = """
+ ./tests/test_trainer_tpu.py
+ --num_cores=8
+ ./tests/test_trainer_tpu.py
+ """.split()
+ with patch.object(sys, "argv", testargs):
+ xla_spawn.main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..9fac0b303850930ab3fcd2fbf5556dca847eb808
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/README.md
@@ -0,0 +1,183 @@
+
+
+# Question answering
+
+This folder contains several scripts that showcase how to fine-tune a 🤗 Transformers model on a question answering dataset,
+like SQuAD.
+
+## Trainer-based scripts
+
+The [`run_qa.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/question-answering/run_qa.py),
+[`run_qa_beam_search.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/question-answering/run_qa_beam_search.py) and [`run_seq2seq_qa.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/question-answering/run_seq2seq_qa.py) leverage the 🤗 [Trainer](https://huggingface.co/transformers/main_classes/trainer.html) for fine-tuning.
+
+### Fine-tuning BERT on SQuAD1.0
+
+The [`run_qa.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/question-answering/run_qa.py) script
+allows to fine-tune any model from our [hub](https://huggingface.co/models) (as long as its architecture has a `ForQuestionAnswering` version in the library) on a question-answering dataset (such as SQuAD, or any other QA dataset available in the `datasets` library, or your own csv/jsonlines files) as long as they are structured the same way as SQuAD. You might need to tweak the data processing inside the script if your data is structured differently.
+
+**Note:** This script only works with models that have a fast tokenizer (backed by the 🤗 Tokenizers library) as it
+uses special features of those tokenizers. You can check if your favorite model has a fast tokenizer in
+[this table](https://huggingface.co/transformers/index.html#supported-frameworks), if it doesn't you can still use the old version of the script which can be found [here](https://github.com/huggingface/transformers/tree/main/examples/legacy/question-answering).
+
+Note that if your dataset contains samples with no possible answers (like SQuAD version 2), you need to pass along the flag `--version_2_with_negative`.
+
+This example code fine-tunes BERT on the SQuAD1.0 dataset. It runs in 24 min (with BERT-base) or 68 min (with BERT-large)
+on a single tesla V100 16GB.
+
+```bash
+python run_qa.py \
+ --model_name_or_path google-bert/bert-base-uncased \
+ --dataset_name squad \
+ --do_train \
+ --do_eval \
+ --per_device_train_batch_size 12 \
+ --learning_rate 3e-5 \
+ --num_train_epochs 2 \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir /tmp/debug_squad/
+```
+
+Training with the previously defined hyper-parameters yields the following results:
+
+```bash
+f1 = 88.52
+exact_match = 81.22
+```
+
+### Fine-tuning XLNet with beam search on SQuAD
+
+The [`run_qa_beam_search.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/question-answering/run_qa_beam_search.py) script is only meant to fine-tune XLNet, which is a special encoder-only Transformer model. The example code below fine-tunes XLNet on the SQuAD1.0 and SQuAD2.0 datasets.
+
+#### Command for SQuAD1.0:
+
+```bash
+python run_qa_beam_search.py \
+ --model_name_or_path xlnet/xlnet-large-cased \
+ --dataset_name squad \
+ --do_train \
+ --do_eval \
+ --learning_rate 3e-5 \
+ --num_train_epochs 2 \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir ./wwm_cased_finetuned_squad/ \
+ --per_device_eval_batch_size=4 \
+ --per_device_train_batch_size=4 \
+ --save_steps 5000
+```
+
+#### Command for SQuAD2.0:
+
+```bash
+export SQUAD_DIR=/path/to/SQUAD
+
+python run_qa_beam_search.py \
+ --model_name_or_path xlnet/xlnet-large-cased \
+ --dataset_name squad_v2 \
+ --do_train \
+ --do_eval \
+ --version_2_with_negative \
+ --learning_rate 3e-5 \
+ --num_train_epochs 4 \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir ./wwm_cased_finetuned_squad/ \
+ --per_device_eval_batch_size=2 \
+ --per_device_train_batch_size=2 \
+ --save_steps 5000
+```
+
+### Fine-tuning T5 on SQuAD2.0
+
+The [`run_seq2seq_qa.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/question-answering/run_seq2seq_qa.py) script is meant for encoder-decoder (also called seq2seq) Transformer models, such as T5 or BART. These
+models are generative, rather than discriminative. This means that they learn to generate the correct answer, rather than predicting the start and end position of the tokens of the answer.
+
+This example code fine-tunes T5 on the SQuAD2.0 dataset.
+
+```bash
+python run_seq2seq_qa.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name squad_v2 \
+ --context_column context \
+ --question_column question \
+ --answer_column answers \
+ --do_train \
+ --do_eval \
+ --per_device_train_batch_size 12 \
+ --learning_rate 3e-5 \
+ --num_train_epochs 2 \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir /tmp/debug_seq2seq_squad/
+```
+
+## Accelerate-based scripts
+
+Based on the scripts `run_qa_no_trainer.py` and `run_qa_beam_search_no_trainer.py`.
+
+Like `run_qa.py` and `run_qa_beam_search.py`, these scripts allow you to fine-tune any of the models supported on a
+SQuAD or a similar dataset, the main difference is that this script exposes the bare training loop, to allow you to quickly experiment and add any customization you would like. It offers less options than the script with `Trainer` (for instance you can easily change the options for the optimizer or the dataloaders directly in the script), but still run in a distributed setup, on TPU and supports mixed precision by leveraging the [🤗 `Accelerate`](https://github.com/huggingface/accelerate) library.
+
+You can use the script normally after installing it:
+
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+then
+
+```bash
+python run_qa_no_trainer.py \
+ --model_name_or_path google-bert/bert-base-uncased \
+ --dataset_name squad \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir ~/tmp/debug_squad
+```
+
+You can then use your usual launchers to run in it in a distributed environment, but the easiest way is to run
+
+```bash
+accelerate config
+```
+
+and reply to the questions asked. Then
+
+```bash
+accelerate test
+```
+
+that will check everything is ready for training. Finally, you can launch training with
+
+```bash
+accelerate launch run_qa_no_trainer.py \
+ --model_name_or_path google-bert/bert-base-uncased \
+ --dataset_name squad \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir ~/tmp/debug_squad
+```
+
+This command is the same and will work for:
+
+- a CPU-only setup
+- a setup with one GPU
+- a distributed training with several GPUs (single or multi node)
+- a training on TPUs
+
+Note that this library is in alpha release so your feedback is more than welcome if you encounter any problem using it.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..c8200d867ec4f79ebb3c2649a5aa3773d0b7eb54
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/requirements.txt
@@ -0,0 +1,4 @@
+accelerate >= 0.12.0
+datasets >= 1.8.0
+torch >= 1.3.0
+evaluate
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/run_qa.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/run_qa.py
new file mode 100644
index 0000000000000000000000000000000000000000..81fcc7b8b70b968a14b5b048e80b7d93f316faf4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/run_qa.py
@@ -0,0 +1,715 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2020 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for question answering using a slightly adapted version of the 🤗 Trainer.
+"""
+# You can also adapt this script on your own question answering task. Pointers for this are left as comments.
+
+import logging
+import os
+import sys
+import warnings
+from dataclasses import dataclass, field
+from typing import Optional
+
+import datasets
+import evaluate
+from datasets import load_dataset
+from trainer_qa import QuestionAnsweringTrainer
+from utils_qa import postprocess_qa_predictions
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForQuestionAnswering,
+ AutoTokenizer,
+ DataCollatorWithPadding,
+ EvalPrediction,
+ HfArgumentParser,
+ PreTrainedTokenizerFast,
+ TrainingArguments,
+ default_data_collator,
+ set_seed,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/question-answering/requirements.txt")
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Path to directory to store the pretrained models downloaded from huggingface.co"},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ test_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input test data file to evaluate the perplexity on (a text file)."},
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ max_seq_length: int = field(
+ default=384,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ pad_to_max_length: bool = field(
+ default=True,
+ metadata={
+ "help": (
+ "Whether to pad all samples to `max_seq_length`. If False, will pad the samples dynamically when"
+ " batching to the maximum length in the batch (which can be faster on GPU but will be slower on TPU)."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_predict_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of prediction examples to this "
+ "value if set."
+ )
+ },
+ )
+ version_2_with_negative: bool = field(
+ default=False, metadata={"help": "If true, some of the examples do not have an answer."}
+ )
+ null_score_diff_threshold: float = field(
+ default=0.0,
+ metadata={
+ "help": (
+ "The threshold used to select the null answer: if the best answer has a score that is less than "
+ "the score of the null answer minus this threshold, the null answer is selected for this example. "
+ "Only useful when `version_2_with_negative=True`."
+ )
+ },
+ )
+ doc_stride: int = field(
+ default=128,
+ metadata={"help": "When splitting up a long document into chunks, how much stride to take between chunks."},
+ )
+ n_best_size: int = field(
+ default=20,
+ metadata={"help": "The total number of n-best predictions to generate when looking for an answer."},
+ )
+ max_answer_length: int = field(
+ default=30,
+ metadata={
+ "help": (
+ "The maximum length of an answer that can be generated. This is needed because the start "
+ "and end predictions are not conditioned on one another."
+ )
+ },
+ )
+
+ def __post_init__(self):
+ if (
+ self.dataset_name is None
+ and self.train_file is None
+ and self.validation_file is None
+ and self.test_file is None
+ ):
+ raise ValueError("Need either a dataset name or a training/validation file/test_file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+ if self.test_file is not None:
+ extension = self.test_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`test_file` should be a csv or a json file."
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_qa", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ datasets.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ if data_args.test_file is not None:
+ data_files["test"] = data_args.test_file
+ extension = data_args.test_file.split(".")[-1]
+ raw_datasets = load_dataset(
+ extension,
+ data_files=data_files,
+ field="data",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=True,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ model = AutoModelForQuestionAnswering.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ # Tokenizer check: this script requires a fast tokenizer.
+ if not isinstance(tokenizer, PreTrainedTokenizerFast):
+ raise ValueError(
+ "This example script only works for models that have a fast tokenizer. Checkout the big table of models at"
+ " https://huggingface.co/transformers/index.html#supported-frameworks to find the model types that meet"
+ " this requirement"
+ )
+
+ # Preprocessing the datasets.
+ # Preprocessing is slightly different for training and evaluation.
+ if training_args.do_train:
+ column_names = raw_datasets["train"].column_names
+ elif training_args.do_eval:
+ column_names = raw_datasets["validation"].column_names
+ else:
+ column_names = raw_datasets["test"].column_names
+ question_column_name = "question" if "question" in column_names else column_names[0]
+ context_column_name = "context" if "context" in column_names else column_names[1]
+ answer_column_name = "answers" if "answers" in column_names else column_names[2]
+
+ # Padding side determines if we do (question|context) or (context|question).
+ pad_on_right = tokenizer.padding_side == "right"
+
+ if data_args.max_seq_length > tokenizer.model_max_length:
+ logger.warning(
+ f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
+ f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
+ )
+ max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
+
+ # Training preprocessing
+ def prepare_train_features(examples):
+ # Some of the questions have lots of whitespace on the left, which is not useful and will make the
+ # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
+ # left whitespace
+ examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
+
+ # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
+ # in one example possible giving several features when a context is long, each of those features having a
+ # context that overlaps a bit the context of the previous feature.
+ tokenized_examples = tokenizer(
+ examples[question_column_name if pad_on_right else context_column_name],
+ examples[context_column_name if pad_on_right else question_column_name],
+ truncation="only_second" if pad_on_right else "only_first",
+ max_length=max_seq_length,
+ stride=data_args.doc_stride,
+ return_overflowing_tokens=True,
+ return_offsets_mapping=True,
+ padding="max_length" if data_args.pad_to_max_length else False,
+ )
+
+ # Since one example might give us several features if it has a long context, we need a map from a feature to
+ # its corresponding example. This key gives us just that.
+ sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
+ # The offset mappings will give us a map from token to character position in the original context. This will
+ # help us compute the start_positions and end_positions.
+ offset_mapping = tokenized_examples.pop("offset_mapping")
+
+ # Let's label those examples!
+ tokenized_examples["start_positions"] = []
+ tokenized_examples["end_positions"] = []
+
+ for i, offsets in enumerate(offset_mapping):
+ # We will label impossible answers with the index of the CLS token.
+ input_ids = tokenized_examples["input_ids"][i]
+ if tokenizer.cls_token_id in input_ids:
+ cls_index = input_ids.index(tokenizer.cls_token_id)
+ elif tokenizer.bos_token_id in input_ids:
+ cls_index = input_ids.index(tokenizer.bos_token_id)
+ else:
+ cls_index = 0
+
+ # Grab the sequence corresponding to that example (to know what is the context and what is the question).
+ sequence_ids = tokenized_examples.sequence_ids(i)
+
+ # One example can give several spans, this is the index of the example containing this span of text.
+ sample_index = sample_mapping[i]
+ answers = examples[answer_column_name][sample_index]
+ # If no answers are given, set the cls_index as answer.
+ if len(answers["answer_start"]) == 0:
+ tokenized_examples["start_positions"].append(cls_index)
+ tokenized_examples["end_positions"].append(cls_index)
+ else:
+ # Start/end character index of the answer in the text.
+ start_char = answers["answer_start"][0]
+ end_char = start_char + len(answers["text"][0])
+
+ # Start token index of the current span in the text.
+ token_start_index = 0
+ while sequence_ids[token_start_index] != (1 if pad_on_right else 0):
+ token_start_index += 1
+
+ # End token index of the current span in the text.
+ token_end_index = len(input_ids) - 1
+ while sequence_ids[token_end_index] != (1 if pad_on_right else 0):
+ token_end_index -= 1
+
+ # Detect if the answer is out of the span (in which case this feature is labeled with the CLS index).
+ if not (offsets[token_start_index][0] <= start_char and offsets[token_end_index][1] >= end_char):
+ tokenized_examples["start_positions"].append(cls_index)
+ tokenized_examples["end_positions"].append(cls_index)
+ else:
+ # Otherwise move the token_start_index and token_end_index to the two ends of the answer.
+ # Note: we could go after the last offset if the answer is the last word (edge case).
+ while token_start_index < len(offsets) and offsets[token_start_index][0] <= start_char:
+ token_start_index += 1
+ tokenized_examples["start_positions"].append(token_start_index - 1)
+ while offsets[token_end_index][1] >= end_char:
+ token_end_index -= 1
+ tokenized_examples["end_positions"].append(token_end_index + 1)
+
+ return tokenized_examples
+
+ if training_args.do_train:
+ if "train" not in raw_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = raw_datasets["train"]
+ if data_args.max_train_samples is not None:
+ # We will select sample from whole data if argument is specified
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+ # Create train feature from dataset
+ with training_args.main_process_first(desc="train dataset map pre-processing"):
+ train_dataset = train_dataset.map(
+ prepare_train_features,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on train dataset",
+ )
+ if data_args.max_train_samples is not None:
+ # Number of samples might increase during Feature Creation, We select only specified max samples
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+
+ # Validation preprocessing
+ def prepare_validation_features(examples):
+ # Some of the questions have lots of whitespace on the left, which is not useful and will make the
+ # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
+ # left whitespace
+ examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
+
+ # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
+ # in one example possible giving several features when a context is long, each of those features having a
+ # context that overlaps a bit the context of the previous feature.
+ tokenized_examples = tokenizer(
+ examples[question_column_name if pad_on_right else context_column_name],
+ examples[context_column_name if pad_on_right else question_column_name],
+ truncation="only_second" if pad_on_right else "only_first",
+ max_length=max_seq_length,
+ stride=data_args.doc_stride,
+ return_overflowing_tokens=True,
+ return_offsets_mapping=True,
+ padding="max_length" if data_args.pad_to_max_length else False,
+ )
+
+ # Since one example might give us several features if it has a long context, we need a map from a feature to
+ # its corresponding example. This key gives us just that.
+ sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
+
+ # For evaluation, we will need to convert our predictions to substrings of the context, so we keep the
+ # corresponding example_id and we will store the offset mappings.
+ tokenized_examples["example_id"] = []
+
+ for i in range(len(tokenized_examples["input_ids"])):
+ # Grab the sequence corresponding to that example (to know what is the context and what is the question).
+ sequence_ids = tokenized_examples.sequence_ids(i)
+ context_index = 1 if pad_on_right else 0
+
+ # One example can give several spans, this is the index of the example containing this span of text.
+ sample_index = sample_mapping[i]
+ tokenized_examples["example_id"].append(examples["id"][sample_index])
+
+ # Set to None the offset_mapping that are not part of the context so it's easy to determine if a token
+ # position is part of the context or not.
+ tokenized_examples["offset_mapping"][i] = [
+ (o if sequence_ids[k] == context_index else None)
+ for k, o in enumerate(tokenized_examples["offset_mapping"][i])
+ ]
+
+ return tokenized_examples
+
+ if training_args.do_eval:
+ if "validation" not in raw_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_examples = raw_datasets["validation"]
+ if data_args.max_eval_samples is not None:
+ # We will select sample from whole data
+ max_eval_samples = min(len(eval_examples), data_args.max_eval_samples)
+ eval_examples = eval_examples.select(range(max_eval_samples))
+ # Validation Feature Creation
+ with training_args.main_process_first(desc="validation dataset map pre-processing"):
+ eval_dataset = eval_examples.map(
+ prepare_validation_features,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on validation dataset",
+ )
+ if data_args.max_eval_samples is not None:
+ # During Feature creation dataset samples might increase, we will select required samples again
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+
+ if training_args.do_predict:
+ if "test" not in raw_datasets:
+ raise ValueError("--do_predict requires a test dataset")
+ predict_examples = raw_datasets["test"]
+ if data_args.max_predict_samples is not None:
+ # We will select sample from whole data
+ predict_examples = predict_examples.select(range(data_args.max_predict_samples))
+ # Predict Feature Creation
+ with training_args.main_process_first(desc="prediction dataset map pre-processing"):
+ predict_dataset = predict_examples.map(
+ prepare_validation_features,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on prediction dataset",
+ )
+ if data_args.max_predict_samples is not None:
+ # During Feature creation dataset samples might increase, we will select required samples again
+ max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
+ predict_dataset = predict_dataset.select(range(max_predict_samples))
+
+ # Data collator
+ # We have already padded to max length if the corresponding flag is True, otherwise we need to pad in the data
+ # collator.
+ data_collator = (
+ default_data_collator
+ if data_args.pad_to_max_length
+ else DataCollatorWithPadding(tokenizer, pad_to_multiple_of=8 if training_args.fp16 else None)
+ )
+
+ # Post-processing:
+ def post_processing_function(examples, features, predictions, stage="eval"):
+ # Post-processing: we match the start logits and end logits to answers in the original context.
+ predictions = postprocess_qa_predictions(
+ examples=examples,
+ features=features,
+ predictions=predictions,
+ version_2_with_negative=data_args.version_2_with_negative,
+ n_best_size=data_args.n_best_size,
+ max_answer_length=data_args.max_answer_length,
+ null_score_diff_threshold=data_args.null_score_diff_threshold,
+ output_dir=training_args.output_dir,
+ log_level=log_level,
+ prefix=stage,
+ )
+ # Format the result to the format the metric expects.
+ if data_args.version_2_with_negative:
+ formatted_predictions = [
+ {"id": str(k), "prediction_text": v, "no_answer_probability": 0.0} for k, v in predictions.items()
+ ]
+ else:
+ formatted_predictions = [{"id": str(k), "prediction_text": v} for k, v in predictions.items()]
+
+ references = [{"id": str(ex["id"]), "answers": ex[answer_column_name]} for ex in examples]
+ return EvalPrediction(predictions=formatted_predictions, label_ids=references)
+
+ if data_args.version_2_with_negative:
+ accepted_best_metrics = ("exact", "f1", "HasAns_exact", "HasAns_f1")
+ else:
+ accepted_best_metrics = ("exact_match", "f1")
+
+ if training_args.load_best_model_at_end and training_args.metric_for_best_model not in accepted_best_metrics:
+ warnings.warn(f"--metric_for_best_model should be set to one of {accepted_best_metrics}")
+
+ metric = evaluate.load(
+ "squad_v2" if data_args.version_2_with_negative else "squad", cache_dir=model_args.cache_dir
+ )
+
+ def compute_metrics(p: EvalPrediction):
+ return metric.compute(predictions=p.predictions, references=p.label_ids)
+
+ # Initialize our Trainer
+ trainer = QuestionAnsweringTrainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset if training_args.do_train else None,
+ eval_dataset=eval_dataset if training_args.do_eval else None,
+ eval_examples=eval_examples if training_args.do_eval else None,
+ processing_class=tokenizer,
+ data_collator=data_collator,
+ post_process_function=post_processing_function,
+ compute_metrics=compute_metrics,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model() # Saves the tokenizer too for easy upload
+
+ metrics = train_result.metrics
+ max_train_samples = (
+ data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
+ )
+ metrics["train_samples"] = min(max_train_samples, len(train_dataset))
+
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+ metrics = trainer.evaluate()
+
+ max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
+ metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ # Prediction
+ if training_args.do_predict:
+ logger.info("*** Predict ***")
+ results = trainer.predict(predict_dataset, predict_examples)
+ metrics = results.metrics
+
+ max_predict_samples = (
+ data_args.max_predict_samples if data_args.max_predict_samples is not None else len(predict_dataset)
+ )
+ metrics["predict_samples"] = min(max_predict_samples, len(predict_dataset))
+
+ trainer.log_metrics("predict", metrics)
+ trainer.save_metrics("predict", metrics)
+
+ kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "question-answering"}
+ if data_args.dataset_name is not None:
+ kwargs["dataset_tags"] = data_args.dataset_name
+ if data_args.dataset_config_name is not None:
+ kwargs["dataset_args"] = data_args.dataset_config_name
+ kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
+ else:
+ kwargs["dataset"] = data_args.dataset_name
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/run_qa_beam_search.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/run_qa_beam_search.py
new file mode 100644
index 0000000000000000000000000000000000000000..4b199a9e8990baa45bde40fa261ac86bfd937e23
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/run_qa_beam_search.py
@@ -0,0 +1,742 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2020 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning XLNet for question answering with beam search using a slightly adapted version of the 🤗 Trainer.
+"""
+# You can also adapt this script on your own question answering task. Pointers for this are left as comments.
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from typing import Optional
+
+import datasets
+import evaluate
+from datasets import load_dataset
+from trainer_qa import QuestionAnsweringTrainer
+from utils_qa import postprocess_qa_predictions_with_beam_search
+
+import transformers
+from transformers import (
+ DataCollatorWithPadding,
+ EvalPrediction,
+ HfArgumentParser,
+ TrainingArguments,
+ XLNetConfig,
+ XLNetForQuestionAnswering,
+ XLNetTokenizerFast,
+ default_data_collator,
+ set_seed,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/question-answering/requirements.txt")
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ test_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input test data file to test the perplexity on (a text file)."},
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ max_seq_length: int = field(
+ default=384,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ pad_to_max_length: bool = field(
+ default=True,
+ metadata={
+ "help": (
+ "Whether to pad all samples to `max_seq_length`. If False, will pad the samples dynamically when"
+ " batching to the maximum length in the batch (which can be faster on GPU but will be slower on TPU)."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_predict_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of prediction examples to this "
+ "value if set."
+ )
+ },
+ )
+ version_2_with_negative: bool = field(
+ default=False, metadata={"help": "If true, some of the examples do not have an answer."}
+ )
+ null_score_diff_threshold: float = field(
+ default=0.0,
+ metadata={
+ "help": (
+ "The threshold used to select the null answer: if the best answer has a score that is less than "
+ "the score of the null answer minus this threshold, the null answer is selected for this example. "
+ "Only useful when `version_2_with_negative=True`."
+ )
+ },
+ )
+ doc_stride: int = field(
+ default=128,
+ metadata={"help": "When splitting up a long document into chunks, how much stride to take between chunks."},
+ )
+ n_best_size: int = field(
+ default=20,
+ metadata={"help": "The total number of n-best predictions to generate when looking for an answer."},
+ )
+ max_answer_length: int = field(
+ default=30,
+ metadata={
+ "help": (
+ "The maximum length of an answer that can be generated. This is needed because the start "
+ "and end predictions are not conditioned on one another."
+ )
+ },
+ )
+
+ def __post_init__(self):
+ if (
+ self.dataset_name is None
+ and self.train_file is None
+ and self.validation_file is None
+ and self.test_file is None
+ ):
+ raise ValueError("Need either a dataset name or a training/validation/test file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+ if self.test_file is not None:
+ extension = self.test_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`test_file` should be a csv or a json file."
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_qa_beam_search", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ datasets.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ if data_args.test_file is not None:
+ data_files["test"] = data_args.test_file
+ extension = data_args.test_file.split(".")[-1]
+ raw_datasets = load_dataset(
+ extension,
+ data_files=data_files,
+ field="data",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config = XLNetConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ )
+ tokenizer = XLNetTokenizerFast.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ )
+ model = XLNetForQuestionAnswering.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ )
+
+ # Preprocessing the datasets.
+ # Preprocessing is slightly different for training and evaluation.
+ if training_args.do_train:
+ column_names = raw_datasets["train"].column_names
+ elif training_args.do_eval:
+ column_names = raw_datasets["validation"].column_names
+ else:
+ column_names = raw_datasets["test"].column_names
+ question_column_name = "question" if "question" in column_names else column_names[0]
+ context_column_name = "context" if "context" in column_names else column_names[1]
+ answer_column_name = "answers" if "answers" in column_names else column_names[2]
+
+ # Padding side determines if we do (question|context) or (context|question).
+ pad_on_right = tokenizer.padding_side == "right"
+
+ if data_args.max_seq_length > tokenizer.model_max_length:
+ logger.warning(
+ f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
+ f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
+ )
+ max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
+
+ # Training preprocessing
+ def prepare_train_features(examples):
+ # Some of the questions have lots of whitespace on the left, which is not useful and will make the
+ # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
+ # left whitespace
+ examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
+
+ # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
+ # in one example possible giving several features when a context is long, each of those features having a
+ # context that overlaps a bit the context of the previous feature.
+ tokenized_examples = tokenizer(
+ examples[question_column_name if pad_on_right else context_column_name],
+ examples[context_column_name if pad_on_right else question_column_name],
+ truncation="only_second" if pad_on_right else "only_first",
+ max_length=max_seq_length,
+ stride=data_args.doc_stride,
+ return_overflowing_tokens=True,
+ return_offsets_mapping=True,
+ return_special_tokens_mask=True,
+ return_token_type_ids=True,
+ padding="max_length",
+ )
+
+ # Since one example might give us several features if it has a long context, we need a map from a feature to
+ # its corresponding example. This key gives us just that.
+ sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
+ # The offset mappings will give us a map from token to character position in the original context. This will
+ # help us compute the start_positions and end_positions.
+ offset_mapping = tokenized_examples.pop("offset_mapping")
+ # The special tokens will help us build the p_mask (which indicates the tokens that can't be in answers).
+ special_tokens = tokenized_examples.pop("special_tokens_mask")
+
+ # Let's label those examples!
+ tokenized_examples["start_positions"] = []
+ tokenized_examples["end_positions"] = []
+ tokenized_examples["is_impossible"] = []
+ tokenized_examples["cls_index"] = []
+ tokenized_examples["p_mask"] = []
+
+ for i, offsets in enumerate(offset_mapping):
+ # We will label impossible answers with the index of the CLS token.
+ input_ids = tokenized_examples["input_ids"][i]
+ if tokenizer.cls_token_id in input_ids:
+ cls_index = input_ids.index(tokenizer.cls_token_id)
+ elif tokenizer.bos_token_id in input_ids:
+ cls_index = input_ids.index(tokenizer.bos_token_id)
+ else:
+ cls_index = 0
+ tokenized_examples["cls_index"].append(cls_index)
+
+ # Grab the sequence corresponding to that example (to know what is the context and what is the question).
+ sequence_ids = tokenized_examples["token_type_ids"][i]
+ for k, s in enumerate(special_tokens[i]):
+ if s:
+ sequence_ids[k] = 3
+ context_idx = 1 if pad_on_right else 0
+
+ # Build the p_mask: non special tokens and context gets 0.0, the others get 1.0.
+ # The cls token gets 1.0 too (for predictions of empty answers).
+ tokenized_examples["p_mask"].append(
+ [
+ 0.0 if (not special_tokens[i][k] and s == context_idx) or k == cls_index else 1.0
+ for k, s in enumerate(sequence_ids)
+ ]
+ )
+
+ # One example can give several spans, this is the index of the example containing this span of text.
+ sample_index = sample_mapping[i]
+ answers = examples[answer_column_name][sample_index]
+ # If no answers are given, set the cls_index as answer.
+ if len(answers["answer_start"]) == 0:
+ tokenized_examples["start_positions"].append(cls_index)
+ tokenized_examples["end_positions"].append(cls_index)
+ tokenized_examples["is_impossible"].append(1.0)
+ else:
+ # Start/end character index of the answer in the text.
+ start_char = answers["answer_start"][0]
+ end_char = start_char + len(answers["text"][0])
+
+ # Start token index of the current span in the text.
+ token_start_index = 0
+ while sequence_ids[token_start_index] != context_idx:
+ token_start_index += 1
+
+ # End token index of the current span in the text.
+ token_end_index = len(input_ids) - 1
+ while sequence_ids[token_end_index] != context_idx:
+ token_end_index -= 1
+ # Detect if the answer is out of the span (in which case this feature is labeled with the CLS index).
+ if not (offsets[token_start_index][0] <= start_char and offsets[token_end_index][1] >= end_char):
+ tokenized_examples["start_positions"].append(cls_index)
+ tokenized_examples["end_positions"].append(cls_index)
+ tokenized_examples["is_impossible"].append(1.0)
+ else:
+ # Otherwise move the token_start_index and token_end_index to the two ends of the answer.
+ # Note: we could go after the last offset if the answer is the last word (edge case).
+ while token_start_index < len(offsets) and offsets[token_start_index][0] <= start_char:
+ token_start_index += 1
+ tokenized_examples["start_positions"].append(token_start_index - 1)
+ while offsets[token_end_index][1] >= end_char:
+ token_end_index -= 1
+ tokenized_examples["end_positions"].append(token_end_index + 1)
+ tokenized_examples["is_impossible"].append(0.0)
+
+ return tokenized_examples
+
+ if training_args.do_train:
+ if "train" not in raw_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = raw_datasets["train"]
+ if data_args.max_train_samples is not None:
+ # Select samples from Dataset, This will help to decrease processing time
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+ # Create Training Features
+ with training_args.main_process_first(desc="train dataset map pre-processing"):
+ train_dataset = train_dataset.map(
+ prepare_train_features,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on train dataset",
+ )
+ if data_args.max_train_samples is not None:
+ # Select samples from dataset again since Feature Creation might increase number of features
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+
+ # Validation preprocessing
+ def prepare_validation_features(examples):
+ # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
+ # in one example possible giving several features when a context is long, each of those features having a
+ # context that overlaps a bit the context of the previous feature.
+ tokenized_examples = tokenizer(
+ examples[question_column_name if pad_on_right else context_column_name],
+ examples[context_column_name if pad_on_right else question_column_name],
+ truncation="only_second" if pad_on_right else "only_first",
+ max_length=max_seq_length,
+ stride=data_args.doc_stride,
+ return_overflowing_tokens=True,
+ return_offsets_mapping=True,
+ return_special_tokens_mask=True,
+ return_token_type_ids=True,
+ padding="max_length",
+ )
+
+ # Since one example might give us several features if it has a long context, we need a map from a feature to
+ # its corresponding example. This key gives us just that.
+ sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
+
+ # The special tokens will help us build the p_mask (which indicates the tokens that can't be in answers).
+ special_tokens = tokenized_examples.pop("special_tokens_mask")
+
+ # For evaluation, we will need to convert our predictions to substrings of the context, so we keep the
+ # corresponding example_id and we will store the offset mappings.
+ tokenized_examples["example_id"] = []
+
+ # We still provide the index of the CLS token and the p_mask to the model, but not the is_impossible label.
+ tokenized_examples["cls_index"] = []
+ tokenized_examples["p_mask"] = []
+
+ for i, input_ids in enumerate(tokenized_examples["input_ids"]):
+ # Find the CLS token in the input ids.
+ if tokenizer.cls_token_id in input_ids:
+ cls_index = input_ids.index(tokenizer.cls_token_id)
+ elif tokenizer.bos_token_id in input_ids:
+ cls_index = input_ids.index(tokenizer.bos_token_id)
+ else:
+ cls_index = 0
+ tokenized_examples["cls_index"].append(cls_index)
+
+ # Grab the sequence corresponding to that example (to know what is the context and what is the question).
+ sequence_ids = tokenized_examples["token_type_ids"][i]
+ for k, s in enumerate(special_tokens[i]):
+ if s:
+ sequence_ids[k] = 3
+ context_idx = 1 if pad_on_right else 0
+
+ # Build the p_mask: non special tokens and context gets 0.0, the others 1.0.
+ tokenized_examples["p_mask"].append(
+ [
+ 0.0 if (not special_tokens[i][k] and s == context_idx) or k == cls_index else 1.0
+ for k, s in enumerate(sequence_ids)
+ ]
+ )
+
+ # One example can give several spans, this is the index of the example containing this span of text.
+ sample_index = sample_mapping[i]
+ tokenized_examples["example_id"].append(examples["id"][sample_index])
+
+ # Set to None the offset_mapping that are not part of the context so it's easy to determine if a token
+ # position is part of the context or not.
+ tokenized_examples["offset_mapping"][i] = [
+ (o if sequence_ids[k] == context_idx else None)
+ for k, o in enumerate(tokenized_examples["offset_mapping"][i])
+ ]
+
+ return tokenized_examples
+
+ if training_args.do_eval:
+ if "validation" not in raw_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_examples = raw_datasets["validation"]
+ if data_args.max_eval_samples is not None:
+ # Selecting Eval Samples from Dataset
+ max_eval_samples = min(len(eval_examples), data_args.max_eval_samples)
+ eval_examples = eval_examples.select(range(max_eval_samples))
+ # Create Features from Eval Dataset
+ with training_args.main_process_first(desc="validation dataset map pre-processing"):
+ eval_dataset = eval_examples.map(
+ prepare_validation_features,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on validation dataset",
+ )
+ if data_args.max_eval_samples is not None:
+ # Selecting Samples from Dataset again since Feature Creation might increase samples size
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+
+ if training_args.do_predict:
+ if "test" not in raw_datasets:
+ raise ValueError("--do_predict requires a test dataset")
+ predict_examples = raw_datasets["test"]
+ if data_args.max_predict_samples is not None:
+ # We will select sample from whole data
+ predict_examples = predict_examples.select(range(data_args.max_predict_samples))
+ # Test Feature Creation
+ with training_args.main_process_first(desc="prediction dataset map pre-processing"):
+ predict_dataset = predict_examples.map(
+ prepare_validation_features,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on prediction dataset",
+ )
+ if data_args.max_predict_samples is not None:
+ # During Feature creation dataset samples might increase, we will select required samples again
+ max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
+ predict_dataset = predict_dataset.select(range(max_predict_samples))
+
+ # Data collator
+ # We have already padded to max length if the corresponding flag is True, otherwise we need to pad in the data
+ # collator.
+ data_collator = (
+ default_data_collator
+ if data_args.pad_to_max_length
+ else DataCollatorWithPadding(tokenizer, pad_to_multiple_of=8 if training_args.fp16 else None)
+ )
+
+ # Post-processing:
+ def post_processing_function(examples, features, predictions, stage="eval"):
+ # Post-processing: we match the start logits and end logits to answers in the original context.
+ predictions, scores_diff_json = postprocess_qa_predictions_with_beam_search(
+ examples=examples,
+ features=features,
+ predictions=predictions,
+ version_2_with_negative=data_args.version_2_with_negative,
+ n_best_size=data_args.n_best_size,
+ max_answer_length=data_args.max_answer_length,
+ start_n_top=model.config.start_n_top,
+ end_n_top=model.config.end_n_top,
+ output_dir=training_args.output_dir,
+ log_level=log_level,
+ prefix=stage,
+ )
+ # Format the result to the format the metric expects.
+ if data_args.version_2_with_negative:
+ formatted_predictions = [
+ {"id": k, "prediction_text": v, "no_answer_probability": scores_diff_json[k]}
+ for k, v in predictions.items()
+ ]
+ else:
+ formatted_predictions = [{"id": k, "prediction_text": v} for k, v in predictions.items()]
+
+ references = [{"id": ex["id"], "answers": ex[answer_column_name]} for ex in examples]
+ return EvalPrediction(predictions=formatted_predictions, label_ids=references)
+
+ metric = evaluate.load(
+ "squad_v2" if data_args.version_2_with_negative else "squad", cache_dir=model_args.cache_dir
+ )
+
+ def compute_metrics(p: EvalPrediction):
+ return metric.compute(predictions=p.predictions, references=p.label_ids)
+
+ # Initialize our Trainer
+ trainer = QuestionAnsweringTrainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset if training_args.do_train else None,
+ eval_dataset=eval_dataset if training_args.do_eval else None,
+ eval_examples=eval_examples if training_args.do_eval else None,
+ processing_class=tokenizer,
+ data_collator=data_collator,
+ post_process_function=post_processing_function,
+ compute_metrics=compute_metrics,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model() # Saves the tokenizer too for easy upload
+
+ metrics = train_result.metrics
+
+ max_train_samples = (
+ data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
+ )
+ metrics["train_samples"] = min(max_train_samples, len(train_dataset))
+
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+ metrics = trainer.evaluate()
+
+ max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
+ metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ # Prediction
+ if training_args.do_predict:
+ logger.info("*** Predict ***")
+ results = trainer.predict(predict_dataset, predict_examples)
+ metrics = results.metrics
+
+ max_predict_samples = (
+ data_args.max_predict_samples if data_args.max_predict_samples is not None else len(predict_dataset)
+ )
+ metrics["predict_samples"] = min(max_predict_samples, len(predict_dataset))
+
+ trainer.log_metrics("predict", metrics)
+ trainer.save_metrics("predict", metrics)
+
+ kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "question-answering"}
+ if data_args.dataset_name is not None:
+ kwargs["dataset_tags"] = data_args.dataset_name
+ if data_args.dataset_config_name is not None:
+ kwargs["dataset_args"] = data_args.dataset_config_name
+ kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
+ else:
+ kwargs["dataset"] = data_args.dataset_name
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/run_qa_beam_search_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/run_qa_beam_search_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..312d8b389dd610f8a479c6ffce63ba50eb8adfac
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/run_qa_beam_search_no_trainer.py
@@ -0,0 +1,1067 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning XLNet for question answering with beam search using 🤗 Accelerate.
+"""
+# You can also adapt this script on your own question answering task. Pointers for this are left as comments.
+
+import argparse
+import json
+import logging
+import math
+import os
+import random
+from pathlib import Path
+
+import datasets
+import evaluate
+import numpy as np
+import torch
+from accelerate import Accelerator
+from accelerate.logging import get_logger
+from accelerate.utils import set_seed
+from datasets import load_dataset
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from tqdm.auto import tqdm
+from utils_qa import postprocess_qa_predictions_with_beam_search
+
+import transformers
+from transformers import (
+ AdamW,
+ DataCollatorWithPadding,
+ EvalPrediction,
+ SchedulerType,
+ XLNetConfig,
+ XLNetForQuestionAnswering,
+ XLNetTokenizerFast,
+ default_data_collator,
+ get_scheduler,
+)
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/question-answering/requirements.txt")
+
+logger = get_logger(__name__)
+
+
+def save_prefixed_metrics(results, output_dir, file_name: str = "all_results.json", metric_key_prefix: str = "eval"):
+ """
+ Save results while prefixing metric names.
+
+ Args:
+ results: (:obj:`dict`):
+ A dictionary of results.
+ output_dir: (:obj:`str`):
+ An output directory.
+ file_name: (:obj:`str`, `optional`, defaults to :obj:`all_results.json`):
+ An output file name.
+ metric_key_prefix: (:obj:`str`, `optional`, defaults to :obj:`eval`):
+ A metric name prefix.
+ """
+ # Prefix all keys with metric_key_prefix + '_'
+ for key in list(results.keys()):
+ if not key.startswith(f"{metric_key_prefix}_"):
+ results[f"{metric_key_prefix}_{key}"] = results.pop(key)
+
+ with open(os.path.join(output_dir, file_name), "w") as f:
+ json.dump(results, f, indent=4)
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Finetune a transformers model on a Question Answering task")
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ default=None,
+ help="The name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--dataset_config_name",
+ type=str,
+ default=None,
+ help="The configuration name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--trust_remote_code",
+ action="store_true",
+ help=(
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
+ )
+ parser.add_argument(
+ "--preprocessing_num_workers", type=int, default=1, help="A csv or a json file containing the training data."
+ )
+ parser.add_argument("--do_predict", action="store_true", help="Eval the question answering model")
+ parser.add_argument(
+ "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
+ )
+ parser.add_argument(
+ "--test_file", type=str, default=None, help="A csv or a json file containing the Prediction data."
+ )
+ parser.add_argument(
+ "--max_seq_length",
+ type=int,
+ default=384,
+ help=(
+ "The maximum total input sequence length after tokenization. Sequences longer than this will be truncated,"
+ " sequences shorter will be padded if `--pad_to_max_length` is passed."
+ ),
+ )
+ parser.add_argument(
+ "--pad_to_max_length",
+ action="store_true",
+ help="If passed, pad all samples to `max_seq_length`. Otherwise, dynamic padding is used.",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=True,
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument(
+ "--doc_stride",
+ type=int,
+ default=128,
+ help="When splitting up a long document into chunks how much stride to take between chunks.",
+ )
+ parser.add_argument(
+ "--n_best_size",
+ type=int,
+ default=20,
+ help="The total number of n-best predictions to generate when looking for an answer.",
+ )
+ parser.add_argument(
+ "--null_score_diff_threshold",
+ type=float,
+ default=0.0,
+ help=(
+ "The threshold used to select the null answer: if the best answer has a score that is less than "
+ "the score of the null answer minus this threshold, the null answer is selected for this example. "
+ "Only useful when `version_2_with_negative=True`."
+ ),
+ )
+ parser.add_argument(
+ "--version_2_with_negative",
+ action="store_true",
+ help="If true, some of the examples do not have an answer.",
+ )
+ parser.add_argument(
+ "--max_answer_length",
+ type=int,
+ default=30,
+ help=(
+ "The maximum length of an answer that can be generated. This is needed because the start "
+ "and end predictions are not conditioned on one another."
+ ),
+ )
+ parser.add_argument(
+ "--max_train_samples",
+ type=int,
+ default=None,
+ help=(
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ ),
+ )
+ parser.add_argument(
+ "--max_eval_samples",
+ type=int,
+ default=None,
+ help=(
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ ),
+ )
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+ parser.add_argument(
+ "--max_predict_samples",
+ type=int,
+ default=None,
+ help="For debugging purposes or quicker training, truncate the number of prediction examples to this",
+ )
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to load in all available experiment trackers from the environment and use them for logging.",
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+ if (
+ args.dataset_name is None
+ and args.train_file is None
+ and args.validation_file is None
+ and args.test_file is None
+ ):
+ raise ValueError("Need either a dataset name or a training/validation/test file.")
+ else:
+ if args.train_file is not None:
+ extension = args.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if args.validation_file is not None:
+ extension = args.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+ if args.test_file is not None:
+ extension = args.test_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`test_file` should be a csv or a json file."
+
+ if args.push_to_hub:
+ assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
+
+ return args
+
+
+def main():
+ args = parse_args()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_qa_beam_search_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will pick up all supported trackers
+ # in the environment
+ accelerator_log_kwargs = {}
+
+ if args.with_tracking:
+ accelerator_log_kwargs["log_with"] = args.report_to
+ accelerator_log_kwargs["project_dir"] = args.output_dir
+
+ accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
+ )
+ else:
+ data_files = {}
+ if args.train_file is not None:
+ data_files["train"] = args.train_file
+ extension = args.train_file.split(".")[-1]
+ if args.validation_file is not None:
+ data_files["validation"] = args.validation_file
+ extension = args.validation_file.split(".")[-1]
+ if args.test_file is not None:
+ data_files["test"] = args.test_file
+ extension = args.test_file.split(".")[-1]
+ raw_datasets = load_dataset(extension, data_files=data_files, field="data")
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+ #
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+
+ config = XLNetConfig.from_pretrained(args.model_name_or_path)
+ tokenizer = XLNetTokenizerFast.from_pretrained(args.model_name_or_path)
+ model = XLNetForQuestionAnswering.from_pretrained(
+ args.model_name_or_path, from_tf=bool(".ckpt" in args.model_name_or_path), config=config
+ )
+
+ # Preprocessing the datasets.
+ # Preprocessing is slightly different for training and evaluation.
+ column_names = raw_datasets["train"].column_names
+
+ question_column_name = "question" if "question" in column_names else column_names[0]
+ context_column_name = "context" if "context" in column_names else column_names[1]
+ answer_column_name = "answers" if "answers" in column_names else column_names[2]
+
+ # Padding side determines if we do (question|context) or (context|question).
+ pad_on_right = tokenizer.padding_side == "right"
+
+ if args.max_seq_length > tokenizer.model_max_length:
+ logger.warning(
+ f"The max_seq_length passed ({args.max_seq_length}) is larger than the maximum length for the "
+ f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
+ )
+
+ max_seq_length = min(args.max_seq_length, tokenizer.model_max_length)
+
+ # Training preprocessing
+ def prepare_train_features(examples):
+ # Some of the questions have lots of whitespace on the left, which is not useful and will make the
+ # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
+ # left whitespace
+ examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
+
+ # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
+ # in one example possible giving several features when a context is long, each of those features having a
+ # context that overlaps a bit the context of the previous feature.
+ tokenized_examples = tokenizer(
+ examples[question_column_name if pad_on_right else context_column_name],
+ examples[context_column_name if pad_on_right else question_column_name],
+ truncation="only_second" if pad_on_right else "only_first",
+ max_length=max_seq_length,
+ stride=args.doc_stride,
+ return_overflowing_tokens=True,
+ return_offsets_mapping=True,
+ return_special_tokens_mask=True,
+ return_token_type_ids=True,
+ padding="max_length",
+ )
+
+ # Since one example might give us several features if it has a long context, we need a map from a feature to
+ # its corresponding example. This key gives us just that.
+ sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
+ # The offset mappings will give us a map from token to character position in the original context. This will
+ # help us compute the start_positions and end_positions.
+ offset_mapping = tokenized_examples.pop("offset_mapping")
+ # The special tokens will help us build the p_mask (which indicates the tokens that can't be in answers).
+ special_tokens = tokenized_examples.pop("special_tokens_mask")
+
+ # Let's label those examples!
+ tokenized_examples["start_positions"] = []
+ tokenized_examples["end_positions"] = []
+ tokenized_examples["is_impossible"] = []
+ tokenized_examples["cls_index"] = []
+ tokenized_examples["p_mask"] = []
+
+ for i, offsets in enumerate(offset_mapping):
+ # We will label impossible answers with the index of the CLS token.
+ input_ids = tokenized_examples["input_ids"][i]
+ if tokenizer.cls_token_id in input_ids:
+ cls_index = input_ids.index(tokenizer.cls_token_id)
+ elif tokenizer.bos_token_id in input_ids:
+ cls_index = input_ids.index(tokenizer.bos_token_id)
+ else:
+ cls_index = 0
+ tokenized_examples["cls_index"].append(cls_index)
+
+ # Grab the sequence corresponding to that example (to know what is the context and what is the question).
+ sequence_ids = tokenized_examples["token_type_ids"][i]
+ for k, s in enumerate(special_tokens[i]):
+ if s:
+ sequence_ids[k] = 3
+ context_idx = 1 if pad_on_right else 0
+
+ # Build the p_mask: non special tokens and context gets 0.0, the others get 1.0.
+ # The cls token gets 1.0 too (for predictions of empty answers).
+ tokenized_examples["p_mask"].append(
+ [
+ 0.0 if (not special_tokens[i][k] and s == context_idx) or k == cls_index else 1.0
+ for k, s in enumerate(sequence_ids)
+ ]
+ )
+
+ # One example can give several spans, this is the index of the example containing this span of text.
+ sample_index = sample_mapping[i]
+ answers = examples[answer_column_name][sample_index]
+ # If no answers are given, set the cls_index as answer.
+ if len(answers["answer_start"]) == 0:
+ tokenized_examples["start_positions"].append(cls_index)
+ tokenized_examples["end_positions"].append(cls_index)
+ tokenized_examples["is_impossible"].append(1.0)
+ else:
+ # Start/end character index of the answer in the text.
+ start_char = answers["answer_start"][0]
+ end_char = start_char + len(answers["text"][0])
+
+ # Start token index of the current span in the text.
+ token_start_index = 0
+ while sequence_ids[token_start_index] != context_idx:
+ token_start_index += 1
+
+ # End token index of the current span in the text.
+ token_end_index = len(input_ids) - 1
+ while sequence_ids[token_end_index] != context_idx:
+ token_end_index -= 1
+ # Detect if the answer is out of the span (in which case this feature is labeled with the CLS index).
+ if not (offsets[token_start_index][0] <= start_char and offsets[token_end_index][1] >= end_char):
+ tokenized_examples["start_positions"].append(cls_index)
+ tokenized_examples["end_positions"].append(cls_index)
+ tokenized_examples["is_impossible"].append(1.0)
+ else:
+ # Otherwise move the token_start_index and token_end_index to the two ends of the answer.
+ # Note: we could go after the last offset if the answer is the last word (edge case).
+ while token_start_index < len(offsets) and offsets[token_start_index][0] <= start_char:
+ token_start_index += 1
+ tokenized_examples["start_positions"].append(token_start_index - 1)
+ while offsets[token_end_index][1] >= end_char:
+ token_end_index -= 1
+ tokenized_examples["end_positions"].append(token_end_index + 1)
+ tokenized_examples["is_impossible"].append(0.0)
+
+ return tokenized_examples
+
+ if "train" not in raw_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = raw_datasets["train"]
+ if args.max_train_samples is not None:
+ # We will select sample from whole data if argument is specified
+ train_dataset = train_dataset.select(range(args.max_train_samples))
+ # Create train feature from dataset
+ with accelerator.main_process_first():
+ train_dataset = train_dataset.map(
+ prepare_train_features,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Running tokenizer on train dataset",
+ )
+ if args.max_train_samples is not None:
+ # Number of samples might increase during Feature Creation, We select only specified max samples
+ train_dataset = train_dataset.select(range(args.max_train_samples))
+
+ # Validation preprocessing
+ def prepare_validation_features(examples):
+ # Some of the questions have lots of whitespace on the left, which is not useful and will make the
+ # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
+ # left whitespace
+ examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
+
+ # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
+ # in one example possible giving several features when a context is long, each of those features having a
+ # context that overlaps a bit the context of the previous feature.
+ tokenized_examples = tokenizer(
+ examples[question_column_name if pad_on_right else context_column_name],
+ examples[context_column_name if pad_on_right else question_column_name],
+ truncation="only_second" if pad_on_right else "only_first",
+ max_length=max_seq_length,
+ stride=args.doc_stride,
+ return_overflowing_tokens=True,
+ return_offsets_mapping=True,
+ return_special_tokens_mask=True,
+ return_token_type_ids=True,
+ padding="max_length",
+ )
+
+ # Since one example might give us several features if it has a long context, we need a map from a feature to
+ # its corresponding example. This key gives us just that.
+ sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
+
+ # The special tokens will help us build the p_mask (which indicates the tokens that can't be in answers).
+ special_tokens = tokenized_examples.pop("special_tokens_mask")
+
+ # For evaluation, we will need to convert our predictions to substrings of the context, so we keep the
+ # corresponding example_id and we will store the offset mappings.
+ tokenized_examples["example_id"] = []
+
+ # We still provide the index of the CLS token and the p_mask to the model, but not the is_impossible label.
+ tokenized_examples["cls_index"] = []
+ tokenized_examples["p_mask"] = []
+
+ for i, input_ids in enumerate(tokenized_examples["input_ids"]):
+ # Find the CLS token in the input ids.
+ if tokenizer.cls_token_id in input_ids:
+ cls_index = input_ids.index(tokenizer.cls_token_id)
+ elif tokenizer.bos_token_id in input_ids:
+ cls_index = input_ids.index(tokenizer.bos_token_id)
+ else:
+ cls_index = 0
+ tokenized_examples["cls_index"].append(cls_index)
+
+ # Grab the sequence corresponding to that example (to know what is the context and what is the question).
+ sequence_ids = tokenized_examples["token_type_ids"][i]
+ for k, s in enumerate(special_tokens[i]):
+ if s:
+ sequence_ids[k] = 3
+ context_idx = 1 if pad_on_right else 0
+
+ # Build the p_mask: non special tokens and context gets 0.0, the others 1.0.
+ tokenized_examples["p_mask"].append(
+ [
+ 0.0 if (not special_tokens[i][k] and s == context_idx) or k == cls_index else 1.0
+ for k, s in enumerate(sequence_ids)
+ ]
+ )
+
+ # One example can give several spans, this is the index of the example containing this span of text.
+ sample_index = sample_mapping[i]
+ tokenized_examples["example_id"].append(examples["id"][sample_index])
+
+ # Set to None the offset_mapping that are not part of the context so it's easy to determine if a token
+ # position is part of the context or not.
+ tokenized_examples["offset_mapping"][i] = [
+ (o if sequence_ids[k] == context_idx else None)
+ for k, o in enumerate(tokenized_examples["offset_mapping"][i])
+ ]
+
+ return tokenized_examples
+
+ if "validation" not in raw_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_examples = raw_datasets["validation"]
+ if args.max_eval_samples is not None:
+ # We will select sample from whole data
+ eval_examples = eval_examples.select(range(args.max_eval_samples))
+ # Validation Feature Creation
+ with accelerator.main_process_first():
+ eval_dataset = eval_examples.map(
+ prepare_validation_features,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Running tokenizer on validation dataset",
+ )
+
+ if args.max_eval_samples is not None:
+ # During Feature creation dataset samples might increase, we will select required samples again
+ eval_dataset = eval_dataset.select(range(args.max_eval_samples))
+
+ if args.do_predict:
+ if "test" not in raw_datasets:
+ raise ValueError("--do_predict requires a test dataset")
+ predict_examples = raw_datasets["test"]
+ if args.max_predict_samples is not None:
+ # We will select sample from whole data
+ predict_examples = predict_examples.select(range(args.max_predict_samples))
+ # Predict Feature Creation
+ with accelerator.main_process_first():
+ predict_dataset = predict_examples.map(
+ prepare_validation_features,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Running tokenizer on prediction dataset",
+ )
+ if args.max_predict_samples is not None:
+ # During Feature creation dataset samples might increase, we will select required samples again
+ predict_dataset = predict_dataset.select(range(args.max_predict_samples))
+
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ # DataLoaders creation:
+ if args.pad_to_max_length:
+ # If padding was already done ot max length, we use the default data collator that will just convert everything
+ # to tensors.
+ data_collator = default_data_collator
+ else:
+ # Otherwise, `DataCollatorWithPadding` will apply dynamic padding for us (by padding to the maximum length of
+ # the samples passed). When using mixed precision, we add `pad_to_multiple_of=8` to pad all tensors to multiple
+ # of 8s, which will enable the use of Tensor Cores on NVIDIA hardware with compute capability >= 7.5 (Volta).
+ # For fp8, we pad to multiple of 16.
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+ data_collator = DataCollatorWithPadding(tokenizer, pad_to_multiple_of=pad_to_multiple_of)
+
+ train_dataloader = DataLoader(
+ train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
+ )
+
+ eval_dataset_for_model = eval_dataset.remove_columns(["example_id", "offset_mapping"])
+ eval_dataloader = DataLoader(
+ eval_dataset_for_model, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size
+ )
+
+ if args.do_predict:
+ predict_dataset_for_model = predict_dataset.remove_columns(["example_id", "offset_mapping"])
+ predict_dataloader = DataLoader(
+ predict_dataset_for_model, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size
+ )
+
+ # Post-processing:
+ def post_processing_function(examples, features, predictions, stage="eval"):
+ # Post-processing: we match the start logits and end logits to answers in the original context.
+ predictions, scores_diff_json = postprocess_qa_predictions_with_beam_search(
+ examples=examples,
+ features=features,
+ predictions=predictions,
+ version_2_with_negative=args.version_2_with_negative,
+ n_best_size=args.n_best_size,
+ max_answer_length=args.max_answer_length,
+ start_n_top=model.config.start_n_top,
+ end_n_top=model.config.end_n_top,
+ output_dir=args.output_dir,
+ prefix=stage,
+ )
+ # Format the result to the format the metric expects.
+ if args.version_2_with_negative:
+ formatted_predictions = [
+ {"id": k, "prediction_text": v, "no_answer_probability": scores_diff_json[k]}
+ for k, v in predictions.items()
+ ]
+ else:
+ formatted_predictions = [{"id": k, "prediction_text": v} for k, v in predictions.items()]
+
+ references = [{"id": ex["id"], "answers": ex[answer_column_name]} for ex in examples]
+ return EvalPrediction(predictions=formatted_predictions, label_ids=references)
+
+ metric = evaluate.load("squad_v2" if args.version_2_with_negative else "squad")
+
+ def create_and_fill_np_array(start_or_end_logits, dataset, max_len):
+ """
+ Create and fill numpy array of size len_of_validation_data * max_length_of_output_tensor
+
+ Args:
+ start_or_end_logits(:obj:`tensor`):
+ This is the output predictions of the model. We can only enter either start or end logits.
+ eval_dataset: Evaluation dataset
+ max_len(:obj:`int`):
+ The maximum length of the output tensor. ( See the model.eval() part for more details )
+ """
+
+ step = 0
+ # create a numpy array and fill it with -100.
+ logits_concat = np.full((len(dataset), max_len), -100, dtype=np.float32)
+ # Now since we have create an array now we will populate it with the outputs gathered using accelerator.gather_for_metrics
+ for i, output_logit in enumerate(start_or_end_logits): # populate columns
+ # We have to fill it such that we have to take the whole tensor and replace it on the newly created array
+ # And after every iteration we have to change the step
+
+ batch_size = output_logit.shape[0]
+ cols = output_logit.shape[1]
+ if step + batch_size < len(dataset):
+ logits_concat[step : step + batch_size, :cols] = output_logit
+ else:
+ logits_concat[step:, :cols] = output_logit[: len(dataset) - step]
+
+ step += batch_size
+
+ return logits_concat
+
+ # Optimizer
+ # Split weights in two groups, one with weight decay and the other not.
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ optimizer = AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
+ num_training_steps=args.max_train_steps
+ if overrode_max_train_steps
+ else args.max_train_steps * accelerator.num_processes,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # We need to initialize the trackers we use, and also store our configuration
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("qa_beam_search_no_trainer", experiment_config)
+
+ # Train!
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ checkpoint_path = args.resume_from_checkpoint
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ checkpoint_path = path
+ path = os.path.basename(checkpoint_path)
+
+ accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
+ accelerator.load_state(checkpoint_path)
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ completed_steps = resume_step // args.gradient_accumulation_steps
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We skip the first `n` batches in the dataloader when resuming from a checkpoint
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ with accelerator.accumulate(model):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+
+ accelerator.backward(loss)
+
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # Checks if the accelerator has performed an optimization step behind the scenes
+ if accelerator.sync_gradients:
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
+ accelerator.save_state(f"step_{completed_steps}")
+
+ if completed_steps >= args.max_train_steps:
+ break
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ # initialize all lists to collect the batches
+ all_start_top_log_probs = []
+ all_start_top_index = []
+ all_end_top_log_probs = []
+ all_end_top_index = []
+ all_cls_logits = []
+
+ model.eval()
+
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+ start_top_log_probs = outputs.start_top_log_probs
+ start_top_index = outputs.start_top_index
+ end_top_log_probs = outputs.end_top_log_probs
+ end_top_index = outputs.end_top_index
+ cls_logits = outputs.cls_logits
+
+ if not args.pad_to_max_length: # necessary to pad predictions and labels for being gathered
+ start_top_log_probs = accelerator.pad_across_processes(start_top_log_probs, dim=1, pad_index=-100)
+ start_top_index = accelerator.pad_across_processes(start_top_index, dim=1, pad_index=-100)
+ end_top_log_probs = accelerator.pad_across_processes(end_top_log_probs, dim=1, pad_index=-100)
+ end_top_index = accelerator.pad_across_processes(end_top_index, dim=1, pad_index=-100)
+ cls_logits = accelerator.pad_across_processes(cls_logits, dim=1, pad_index=-100)
+
+ all_start_top_log_probs.append(accelerator.gather_for_metrics(start_top_log_probs).cpu().numpy())
+ all_start_top_index.append(accelerator.gather_for_metrics(start_top_index).cpu().numpy())
+ all_end_top_log_probs.append(accelerator.gather_for_metrics(end_top_log_probs).cpu().numpy())
+ all_end_top_index.append(accelerator.gather_for_metrics(end_top_index).cpu().numpy())
+ all_cls_logits.append(accelerator.gather_for_metrics(cls_logits).cpu().numpy())
+
+ max_len = max([x.shape[1] for x in all_end_top_log_probs]) # Get the max_length of the tensor
+
+ # concatenate all numpy arrays collected above
+ start_top_log_probs_concat = create_and_fill_np_array(all_start_top_log_probs, eval_dataset, max_len)
+ start_top_index_concat = create_and_fill_np_array(all_start_top_index, eval_dataset, max_len)
+ end_top_log_probs_concat = create_and_fill_np_array(all_end_top_log_probs, eval_dataset, max_len)
+ end_top_index_concat = create_and_fill_np_array(all_end_top_index, eval_dataset, max_len)
+ cls_logits_concat = np.concatenate(all_cls_logits, axis=0)
+
+ # delete the list of numpy arrays
+ del start_top_log_probs
+ del start_top_index
+ del end_top_log_probs
+ del end_top_index
+ del cls_logits
+
+ outputs_numpy = (
+ start_top_log_probs_concat,
+ start_top_index_concat,
+ end_top_log_probs_concat,
+ end_top_index_concat,
+ cls_logits_concat,
+ )
+ prediction = post_processing_function(eval_examples, eval_dataset, outputs_numpy)
+ eval_metric = metric.compute(predictions=prediction.predictions, references=prediction.label_ids)
+ logger.info(f"Evaluation metrics: {eval_metric}")
+
+ if args.do_predict:
+ # initialize all lists to collect the batches
+
+ all_start_top_log_probs = []
+ all_start_top_index = []
+ all_end_top_log_probs = []
+ all_end_top_index = []
+ all_cls_logits = []
+
+ model.eval()
+
+ for step, batch in enumerate(predict_dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+ start_top_log_probs = outputs.start_top_log_probs
+ start_top_index = outputs.start_top_index
+ end_top_log_probs = outputs.end_top_log_probs
+ end_top_index = outputs.end_top_index
+ cls_logits = outputs.cls_logits
+
+ if not args.pad_to_max_length: # necessary to pad predictions and labels for being gathered
+ start_top_log_probs = accelerator.pad_across_processes(start_top_log_probs, dim=1, pad_index=-100)
+ start_top_index = accelerator.pad_across_processes(start_top_index, dim=1, pad_index=-100)
+ end_top_log_probs = accelerator.pad_across_processes(end_top_log_probs, dim=1, pad_index=-100)
+ end_top_index = accelerator.pad_across_processes(end_top_index, dim=1, pad_index=-100)
+ cls_logits = accelerator.pad_across_processes(cls_logits, dim=1, pad_index=-100)
+
+ all_start_top_log_probs.append(accelerator.gather_for_metrics(start_top_log_probs).cpu().numpy())
+ all_start_top_index.append(accelerator.gather_for_metrics(start_top_index).cpu().numpy())
+ all_end_top_log_probs.append(accelerator.gather_for_metrics(end_top_log_probs).cpu().numpy())
+ all_end_top_index.append(accelerator.gather_for_metrics(end_top_index).cpu().numpy())
+ all_cls_logits.append(accelerator.gather_for_metrics(cls_logits).cpu().numpy())
+
+ max_len = max([x.shape[1] for x in all_end_top_log_probs]) # Get the max_length of the tensor
+
+ # concatenate all numpy arrays collected above
+ start_top_log_probs_concat = create_and_fill_np_array(all_start_top_log_probs, predict_dataset, max_len)
+ start_top_index_concat = create_and_fill_np_array(all_start_top_index, predict_dataset, max_len)
+ end_top_log_probs_concat = create_and_fill_np_array(all_end_top_log_probs, predict_dataset, max_len)
+ end_top_index_concat = create_and_fill_np_array(all_end_top_index, predict_dataset, max_len)
+ cls_logits_concat = np.concatenate(all_cls_logits, axis=0)
+
+ # delete the list of numpy arrays
+ del start_top_log_probs
+ del start_top_index
+ del end_top_log_probs
+ del end_top_index
+ del cls_logits
+
+ outputs_numpy = (
+ start_top_log_probs_concat,
+ start_top_index_concat,
+ end_top_log_probs_concat,
+ end_top_index_concat,
+ cls_logits_concat,
+ )
+
+ prediction = post_processing_function(predict_examples, predict_dataset, outputs_numpy)
+ predict_metric = metric.compute(predictions=prediction.predictions, references=prediction.label_ids)
+ logger.info(f"Predict metrics: {predict_metric}")
+
+ if args.with_tracking:
+ log = {
+ "squad_v2" if args.version_2_with_negative else "squad": eval_metric,
+ "train_loss": total_loss,
+ "epoch": epoch,
+ "step": completed_steps,
+ }
+ if args.do_predict:
+ log["squad_v2_predict" if args.version_2_with_negative else "squad_predict"] = predict_metric
+
+ accelerator.log(log)
+
+ if args.checkpointing_steps == "epoch":
+ accelerator.save_state(f"epoch_{epoch}")
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ if args.push_to_hub:
+ api.upload_folder(
+ commit_message="End of training",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ logger.info(json.dumps(eval_metric, indent=4))
+ save_prefixed_metrics(eval_metric, args.output_dir)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/run_qa_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/run_qa_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..da448c37f2c4d6d8ee56141c8149f32b1476c443
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/run_qa_no_trainer.py
@@ -0,0 +1,1044 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning a 🤗 Transformers model for question answering using 🤗 Accelerate.
+"""
+# You can also adapt this script on your own question answering task. Pointers for this are left as comments.
+
+import argparse
+import json
+import logging
+import math
+import os
+import random
+from pathlib import Path
+
+import datasets
+import evaluate
+import numpy as np
+import torch
+from accelerate import Accelerator
+from accelerate.logging import get_logger
+from accelerate.utils import set_seed
+from datasets import load_dataset
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from tqdm.auto import tqdm
+from utils_qa import postprocess_qa_predictions
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ MODEL_MAPPING,
+ AutoConfig,
+ AutoModelForQuestionAnswering,
+ AutoTokenizer,
+ DataCollatorWithPadding,
+ EvalPrediction,
+ SchedulerType,
+ default_data_collator,
+ get_scheduler,
+)
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/question-answering/requirements.txt")
+
+logger = get_logger(__name__)
+# You should update this to your particular problem to have better documentation of `model_type`
+MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+def save_prefixed_metrics(results, output_dir, file_name: str = "all_results.json", metric_key_prefix: str = "eval"):
+ """
+ Save results while prefixing metric names.
+
+ Args:
+ results: (:obj:`dict`):
+ A dictionary of results.
+ output_dir: (:obj:`str`):
+ An output directory.
+ file_name: (:obj:`str`, `optional`, defaults to :obj:`all_results.json`):
+ An output file name.
+ metric_key_prefix: (:obj:`str`, `optional`, defaults to :obj:`eval`):
+ A metric name prefix.
+ """
+ # Prefix all keys with metric_key_prefix + '_'
+ for key in list(results.keys()):
+ if not key.startswith(f"{metric_key_prefix}_"):
+ results[f"{metric_key_prefix}_{key}"] = results.pop(key)
+
+ with open(os.path.join(output_dir, file_name), "w") as f:
+ json.dump(results, f, indent=4)
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Finetune a transformers model on a Question Answering task")
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ default=None,
+ help="The name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--dataset_config_name",
+ type=str,
+ default=None,
+ help="The configuration name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
+ )
+ parser.add_argument(
+ "--preprocessing_num_workers", type=int, default=1, help="A csv or a json file containing the training data."
+ )
+ parser.add_argument("--do_predict", action="store_true", help="To do prediction on the question answering model")
+ parser.add_argument(
+ "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
+ )
+ parser.add_argument(
+ "--test_file", type=str, default=None, help="A csv or a json file containing the Prediction data."
+ )
+ parser.add_argument(
+ "--max_seq_length",
+ type=int,
+ default=384,
+ help=(
+ "The maximum total input sequence length after tokenization. Sequences longer than this will be truncated,"
+ " sequences shorter will be padded if `--pad_to_max_length` is passed."
+ ),
+ )
+ parser.add_argument(
+ "--pad_to_max_length",
+ action="store_true",
+ help="If passed, pad all samples to `max_seq_length`. Otherwise, dynamic padding is used.",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=False,
+ )
+ parser.add_argument(
+ "--config_name",
+ type=str,
+ default=None,
+ help="Pretrained config name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ type=str,
+ default=None,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--use_slow_tokenizer",
+ action="store_true",
+ help="If passed, will use a slow tokenizer (not backed by the 🤗 Tokenizers library).",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument(
+ "--doc_stride",
+ type=int,
+ default=128,
+ help="When splitting up a long document into chunks how much stride to take between chunks.",
+ )
+ parser.add_argument(
+ "--n_best_size",
+ type=int,
+ default=20,
+ help="The total number of n-best predictions to generate when looking for an answer.",
+ )
+ parser.add_argument(
+ "--null_score_diff_threshold",
+ type=float,
+ default=0.0,
+ help=(
+ "The threshold used to select the null answer: if the best answer has a score that is less than "
+ "the score of the null answer minus this threshold, the null answer is selected for this example. "
+ "Only useful when `version_2_with_negative=True`."
+ ),
+ )
+ parser.add_argument(
+ "--version_2_with_negative",
+ action="store_true",
+ help="If true, some of the examples do not have an answer.",
+ )
+ parser.add_argument(
+ "--max_answer_length",
+ type=int,
+ default=30,
+ help=(
+ "The maximum length of an answer that can be generated. This is needed because the start "
+ "and end predictions are not conditioned on one another."
+ ),
+ )
+ parser.add_argument(
+ "--max_train_samples",
+ type=int,
+ default=None,
+ help=(
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ ),
+ )
+ parser.add_argument(
+ "--max_eval_samples",
+ type=int,
+ default=None,
+ help=(
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ ),
+ )
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+ parser.add_argument(
+ "--max_predict_samples",
+ type=int,
+ default=None,
+ help="For debugging purposes or quicker training, truncate the number of prediction examples to this",
+ )
+ parser.add_argument(
+ "--model_type",
+ type=str,
+ default=None,
+ help="Model type to use if training from scratch.",
+ choices=MODEL_TYPES,
+ )
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--trust_remote_code",
+ action="store_true",
+ help=(
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+ if (
+ args.dataset_name is None
+ and args.train_file is None
+ and args.validation_file is None
+ and args.test_file is None
+ ):
+ raise ValueError("Need either a dataset name or a training/validation/test file.")
+ else:
+ if args.train_file is not None:
+ extension = args.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if args.validation_file is not None:
+ extension = args.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+ if args.test_file is not None:
+ extension = args.test_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`test_file` should be a csv or a json file."
+
+ if args.push_to_hub:
+ assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
+
+ return args
+
+
+def main():
+ args = parse_args()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_qa_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+ accelerator_log_kwargs = {}
+
+ if args.with_tracking:
+ accelerator_log_kwargs["log_with"] = args.report_to
+ accelerator_log_kwargs["project_dir"] = args.output_dir
+
+ accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
+ )
+ else:
+ data_files = {}
+ if args.train_file is not None:
+ data_files["train"] = args.train_file
+ extension = args.train_file.split(".")[-1]
+ if args.validation_file is not None:
+ data_files["validation"] = args.validation_file
+ extension = args.validation_file.split(".")[-1]
+ if args.test_file is not None:
+ data_files["test"] = args.test_file
+ extension = args.test_file.split(".")[-1]
+ raw_datasets = load_dataset(extension, data_files=data_files, field="data")
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+ #
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+
+ if args.config_name:
+ config = AutoConfig.from_pretrained(args.config_name, trust_remote_code=args.trust_remote_code)
+ elif args.model_name_or_path:
+ config = AutoConfig.from_pretrained(args.model_name_or_path, trust_remote_code=args.trust_remote_code)
+ else:
+ config = CONFIG_MAPPING[args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ if args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.tokenizer_name, use_fast=True, trust_remote_code=args.trust_remote_code
+ )
+ elif args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.model_name_or_path, use_fast=True, trust_remote_code=args.trust_remote_code
+ )
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if args.model_name_or_path:
+ model = AutoModelForQuestionAnswering.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ trust_remote_code=args.trust_remote_code,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = AutoModelForQuestionAnswering.from_config(config, trust_remote_code=args.trust_remote_code)
+
+ # Preprocessing the datasets.
+ # Preprocessing is slightly different for training and evaluation.
+
+ column_names = raw_datasets["train"].column_names
+
+ question_column_name = "question" if "question" in column_names else column_names[0]
+ context_column_name = "context" if "context" in column_names else column_names[1]
+ answer_column_name = "answers" if "answers" in column_names else column_names[2]
+
+ # Padding side determines if we do (question|context) or (context|question).
+ pad_on_right = tokenizer.padding_side == "right"
+
+ if args.max_seq_length > tokenizer.model_max_length:
+ logger.warning(
+ f"The max_seq_length passed ({args.max_seq_length}) is larger than the maximum length for the "
+ f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
+ )
+
+ max_seq_length = min(args.max_seq_length, tokenizer.model_max_length)
+
+ # Training preprocessing
+ def prepare_train_features(examples):
+ # Some of the questions have lots of whitespace on the left, which is not useful and will make the
+ # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
+ # left whitespace
+ examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
+
+ # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
+ # in one example possible giving several features when a context is long, each of those features having a
+ # context that overlaps a bit the context of the previous feature.
+ tokenized_examples = tokenizer(
+ examples[question_column_name if pad_on_right else context_column_name],
+ examples[context_column_name if pad_on_right else question_column_name],
+ truncation="only_second" if pad_on_right else "only_first",
+ max_length=max_seq_length,
+ stride=args.doc_stride,
+ return_overflowing_tokens=True,
+ return_offsets_mapping=True,
+ padding="max_length" if args.pad_to_max_length else False,
+ )
+
+ # Since one example might give us several features if it has a long context, we need a map from a feature to
+ # its corresponding example. This key gives us just that.
+ sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
+ # The offset mappings will give us a map from token to character position in the original context. This will
+ # help us compute the start_positions and end_positions.
+ offset_mapping = tokenized_examples.pop("offset_mapping")
+
+ # Let's label those examples!
+ tokenized_examples["start_positions"] = []
+ tokenized_examples["end_positions"] = []
+
+ for i, offsets in enumerate(offset_mapping):
+ # We will label impossible answers with the index of the CLS token.
+ input_ids = tokenized_examples["input_ids"][i]
+ if tokenizer.cls_token_id in input_ids:
+ cls_index = input_ids.index(tokenizer.cls_token_id)
+ elif tokenizer.bos_token_id in input_ids:
+ cls_index = input_ids.index(tokenizer.bos_token_id)
+ else:
+ cls_index = 0
+
+ # Grab the sequence corresponding to that example (to know what is the context and what is the question).
+ sequence_ids = tokenized_examples.sequence_ids(i)
+
+ # One example can give several spans, this is the index of the example containing this span of text.
+ sample_index = sample_mapping[i]
+ answers = examples[answer_column_name][sample_index]
+ # If no answers are given, set the cls_index as answer.
+ if len(answers["answer_start"]) == 0:
+ tokenized_examples["start_positions"].append(cls_index)
+ tokenized_examples["end_positions"].append(cls_index)
+ else:
+ # Start/end character index of the answer in the text.
+ start_char = answers["answer_start"][0]
+ end_char = start_char + len(answers["text"][0])
+
+ # Start token index of the current span in the text.
+ token_start_index = 0
+ while sequence_ids[token_start_index] != (1 if pad_on_right else 0):
+ token_start_index += 1
+
+ # End token index of the current span in the text.
+ token_end_index = len(input_ids) - 1
+ while sequence_ids[token_end_index] != (1 if pad_on_right else 0):
+ token_end_index -= 1
+
+ # Detect if the answer is out of the span (in which case this feature is labeled with the CLS index).
+ if not (offsets[token_start_index][0] <= start_char and offsets[token_end_index][1] >= end_char):
+ tokenized_examples["start_positions"].append(cls_index)
+ tokenized_examples["end_positions"].append(cls_index)
+ else:
+ # Otherwise move the token_start_index and token_end_index to the two ends of the answer.
+ # Note: we could go after the last offset if the answer is the last word (edge case).
+ while token_start_index < len(offsets) and offsets[token_start_index][0] <= start_char:
+ token_start_index += 1
+ tokenized_examples["start_positions"].append(token_start_index - 1)
+ while offsets[token_end_index][1] >= end_char:
+ token_end_index -= 1
+ tokenized_examples["end_positions"].append(token_end_index + 1)
+
+ return tokenized_examples
+
+ if "train" not in raw_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = raw_datasets["train"]
+ if args.max_train_samples is not None:
+ # We will select sample from whole data if argument is specified
+ train_dataset = train_dataset.select(range(args.max_train_samples))
+
+ # Create train feature from dataset
+ with accelerator.main_process_first():
+ train_dataset = train_dataset.map(
+ prepare_train_features,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Running tokenizer on train dataset",
+ )
+ if args.max_train_samples is not None:
+ # Number of samples might increase during Feature Creation, We select only specified max samples
+ train_dataset = train_dataset.select(range(args.max_train_samples))
+
+ # Validation preprocessing
+ def prepare_validation_features(examples):
+ # Some of the questions have lots of whitespace on the left, which is not useful and will make the
+ # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
+ # left whitespace
+ examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
+
+ # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
+ # in one example possible giving several features when a context is long, each of those features having a
+ # context that overlaps a bit the context of the previous feature.
+ tokenized_examples = tokenizer(
+ examples[question_column_name if pad_on_right else context_column_name],
+ examples[context_column_name if pad_on_right else question_column_name],
+ truncation="only_second" if pad_on_right else "only_first",
+ max_length=max_seq_length,
+ stride=args.doc_stride,
+ return_overflowing_tokens=True,
+ return_offsets_mapping=True,
+ padding="max_length" if args.pad_to_max_length else False,
+ )
+
+ # Since one example might give us several features if it has a long context, we need a map from a feature to
+ # its corresponding example. This key gives us just that.
+ sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
+
+ # For evaluation, we will need to convert our predictions to substrings of the context, so we keep the
+ # corresponding example_id and we will store the offset mappings.
+ tokenized_examples["example_id"] = []
+
+ for i in range(len(tokenized_examples["input_ids"])):
+ # Grab the sequence corresponding to that example (to know what is the context and what is the question).
+ sequence_ids = tokenized_examples.sequence_ids(i)
+ context_index = 1 if pad_on_right else 0
+
+ # One example can give several spans, this is the index of the example containing this span of text.
+ sample_index = sample_mapping[i]
+ tokenized_examples["example_id"].append(examples["id"][sample_index])
+
+ # Set to None the offset_mapping that are not part of the context so it's easy to determine if a token
+ # position is part of the context or not.
+ tokenized_examples["offset_mapping"][i] = [
+ (o if sequence_ids[k] == context_index else None)
+ for k, o in enumerate(tokenized_examples["offset_mapping"][i])
+ ]
+
+ return tokenized_examples
+
+ if "validation" not in raw_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_examples = raw_datasets["validation"]
+ if args.max_eval_samples is not None:
+ # We will select sample from whole data
+ eval_examples = eval_examples.select(range(args.max_eval_samples))
+ # Validation Feature Creation
+ with accelerator.main_process_first():
+ eval_dataset = eval_examples.map(
+ prepare_validation_features,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Running tokenizer on validation dataset",
+ )
+
+ if args.max_eval_samples is not None:
+ # During Feature creation dataset samples might increase, we will select required samples again
+ eval_dataset = eval_dataset.select(range(args.max_eval_samples))
+
+ if args.do_predict:
+ if "test" not in raw_datasets:
+ raise ValueError("--do_predict requires a test dataset")
+ predict_examples = raw_datasets["test"]
+ if args.max_predict_samples is not None:
+ # We will select sample from whole data
+ predict_examples = predict_examples.select(range(args.max_predict_samples))
+ # Predict Feature Creation
+ with accelerator.main_process_first():
+ predict_dataset = predict_examples.map(
+ prepare_validation_features,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Running tokenizer on prediction dataset",
+ )
+ if args.max_predict_samples is not None:
+ # During Feature creation dataset samples might increase, we will select required samples again
+ predict_dataset = predict_dataset.select(range(args.max_predict_samples))
+
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ # DataLoaders creation:
+ if args.pad_to_max_length:
+ # If padding was already done ot max length, we use the default data collator that will just convert everything
+ # to tensors.
+ data_collator = default_data_collator
+ else:
+ # Otherwise, `DataCollatorWithPadding` will apply dynamic padding for us (by padding to the maximum length of
+ # the samples passed). When using mixed precision, we add `pad_to_multiple_of=8` to pad all tensors to multiple
+ # of 8s, which will enable the use of Tensor Cores on NVIDIA hardware with compute capability >= 7.5 (Volta).
+ # For fp8, we pad to multiple of 16.
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+ data_collator = DataCollatorWithPadding(tokenizer, pad_to_multiple_of=pad_to_multiple_of)
+
+ train_dataloader = DataLoader(
+ train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
+ )
+
+ eval_dataset_for_model = eval_dataset.remove_columns(["example_id", "offset_mapping"])
+ eval_dataloader = DataLoader(
+ eval_dataset_for_model, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size
+ )
+
+ if args.do_predict:
+ predict_dataset_for_model = predict_dataset.remove_columns(["example_id", "offset_mapping"])
+ predict_dataloader = DataLoader(
+ predict_dataset_for_model, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size
+ )
+
+ # Post-processing:
+ def post_processing_function(examples, features, predictions, stage="eval"):
+ # Post-processing: we match the start logits and end logits to answers in the original context.
+ predictions = postprocess_qa_predictions(
+ examples=examples,
+ features=features,
+ predictions=predictions,
+ version_2_with_negative=args.version_2_with_negative,
+ n_best_size=args.n_best_size,
+ max_answer_length=args.max_answer_length,
+ null_score_diff_threshold=args.null_score_diff_threshold,
+ output_dir=args.output_dir,
+ prefix=stage,
+ )
+ # Format the result to the format the metric expects.
+ if args.version_2_with_negative:
+ formatted_predictions = [
+ {"id": k, "prediction_text": v, "no_answer_probability": 0.0} for k, v in predictions.items()
+ ]
+ else:
+ formatted_predictions = [{"id": k, "prediction_text": v} for k, v in predictions.items()]
+
+ references = [{"id": ex["id"], "answers": ex[answer_column_name]} for ex in examples]
+ return EvalPrediction(predictions=formatted_predictions, label_ids=references)
+
+ metric = evaluate.load("squad_v2" if args.version_2_with_negative else "squad")
+
+ # Create and fill numpy array of size len_of_validation_data * max_length_of_output_tensor
+ def create_and_fill_np_array(start_or_end_logits, dataset, max_len):
+ """
+ Create and fill numpy array of size len_of_validation_data * max_length_of_output_tensor
+
+ Args:
+ start_or_end_logits(:obj:`tensor`):
+ This is the output predictions of the model. We can only enter either start or end logits.
+ eval_dataset: Evaluation dataset
+ max_len(:obj:`int`):
+ The maximum length of the output tensor. ( See the model.eval() part for more details )
+ """
+
+ step = 0
+ # create a numpy array and fill it with -100.
+ logits_concat = np.full((len(dataset), max_len), -100, dtype=np.float64)
+ # Now since we have create an array now we will populate it with the outputs gathered using accelerator.gather_for_metrics
+ for i, output_logit in enumerate(start_or_end_logits): # populate columns
+ # We have to fill it such that we have to take the whole tensor and replace it on the newly created array
+ # And after every iteration we have to change the step
+
+ batch_size = output_logit.shape[0]
+ cols = output_logit.shape[1]
+
+ if step + batch_size < len(dataset):
+ logits_concat[step : step + batch_size, :cols] = output_logit
+ else:
+ logits_concat[step:, :cols] = output_logit[: len(dataset) - step]
+
+ step += batch_size
+
+ return logits_concat
+
+ # Optimizer
+ # Split weights in two groups, one with weight decay and the other not.
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
+ num_training_steps=args.max_train_steps
+ if overrode_max_train_steps
+ else args.max_train_steps * accelerator.num_processes,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("qa_no_trainer", experiment_config)
+
+ # Train!
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ checkpoint_path = args.resume_from_checkpoint
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ checkpoint_path = path
+ path = os.path.basename(checkpoint_path)
+
+ accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
+ accelerator.load_state(checkpoint_path)
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ completed_steps = resume_step // args.gradient_accumulation_steps
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We skip the first `n` batches in the dataloader when resuming from a checkpoint
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ with accelerator.accumulate(model):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # Checks if the accelerator has performed an optimization step behind the scenes
+ if accelerator.sync_gradients:
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if completed_steps >= args.max_train_steps:
+ break
+
+ if args.checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ # Evaluation
+ logger.info("***** Running Evaluation *****")
+ logger.info(f" Num examples = {len(eval_dataset)}")
+ logger.info(f" Batch size = {args.per_device_eval_batch_size}")
+
+ all_start_logits = []
+ all_end_logits = []
+
+ model.eval()
+
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+ start_logits = outputs.start_logits
+ end_logits = outputs.end_logits
+
+ if not args.pad_to_max_length: # necessary to pad predictions and labels for being gathered
+ start_logits = accelerator.pad_across_processes(start_logits, dim=1, pad_index=-100)
+ end_logits = accelerator.pad_across_processes(end_logits, dim=1, pad_index=-100)
+
+ all_start_logits.append(accelerator.gather_for_metrics(start_logits).cpu().numpy())
+ all_end_logits.append(accelerator.gather_for_metrics(end_logits).cpu().numpy())
+
+ max_len = max([x.shape[1] for x in all_start_logits]) # Get the max_length of the tensor
+
+ # concatenate the numpy array
+ start_logits_concat = create_and_fill_np_array(all_start_logits, eval_dataset, max_len)
+ end_logits_concat = create_and_fill_np_array(all_end_logits, eval_dataset, max_len)
+
+ # delete the list of numpy arrays
+ del all_start_logits
+ del all_end_logits
+
+ outputs_numpy = (start_logits_concat, end_logits_concat)
+ prediction = post_processing_function(eval_examples, eval_dataset, outputs_numpy)
+ eval_metric = metric.compute(predictions=prediction.predictions, references=prediction.label_ids)
+ logger.info(f"Evaluation metrics: {eval_metric}")
+
+ # Prediction
+ if args.do_predict:
+ logger.info("***** Running Prediction *****")
+ logger.info(f" Num examples = {len(predict_dataset)}")
+ logger.info(f" Batch size = {args.per_device_eval_batch_size}")
+
+ all_start_logits = []
+ all_end_logits = []
+
+ model.eval()
+
+ for step, batch in enumerate(predict_dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+ start_logits = outputs.start_logits
+ end_logits = outputs.end_logits
+
+ if not args.pad_to_max_length: # necessary to pad predictions and labels for being gathered
+ start_logits = accelerator.pad_across_processes(start_logits, dim=1, pad_index=-100)
+ end_logits = accelerator.pad_across_processes(end_logits, dim=1, pad_index=-100)
+
+ all_start_logits.append(accelerator.gather_for_metrics(start_logits).cpu().numpy())
+ all_end_logits.append(accelerator.gather_for_metrics(end_logits).cpu().numpy())
+
+ max_len = max([x.shape[1] for x in all_start_logits]) # Get the max_length of the tensor
+ # concatenate the numpy array
+ start_logits_concat = create_and_fill_np_array(all_start_logits, predict_dataset, max_len)
+ end_logits_concat = create_and_fill_np_array(all_end_logits, predict_dataset, max_len)
+
+ # delete the list of numpy arrays
+ del all_start_logits
+ del all_end_logits
+
+ outputs_numpy = (start_logits_concat, end_logits_concat)
+ prediction = post_processing_function(predict_examples, predict_dataset, outputs_numpy)
+ predict_metric = metric.compute(predictions=prediction.predictions, references=prediction.label_ids)
+ logger.info(f"Predict metrics: {predict_metric}")
+
+ if args.with_tracking:
+ log = {
+ "squad_v2" if args.version_2_with_negative else "squad": eval_metric,
+ "train_loss": total_loss.item() / len(train_dataloader),
+ "epoch": epoch,
+ "step": completed_steps,
+ }
+ if args.do_predict:
+ log["squad_v2_predict" if args.version_2_with_negative else "squad_predict"] = predict_metric
+
+ accelerator.log(log, step=completed_steps)
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ if args.push_to_hub:
+ api.upload_folder(
+ commit_message="End of training",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+ logger.info(json.dumps(eval_metric, indent=4))
+ save_prefixed_metrics(eval_metric, args.output_dir)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/run_seq2seq_qa.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/run_seq2seq_qa.py
new file mode 100644
index 0000000000000000000000000000000000000000..cd6204c467c2a2bb0ad065623e218599879c576f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/run_seq2seq_qa.py
@@ -0,0 +1,743 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library's seq2seq models for question answering using the 🤗 Seq2SeqTrainer.
+"""
+# You can also adapt this script on your own question answering task. Pointers for this are left as comments.
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from typing import List, Optional, Tuple
+
+import datasets
+import evaluate
+import numpy as np
+from datasets import load_dataset
+from trainer_seq2seq_qa import QuestionAnsweringSeq2SeqTrainer
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForSeq2SeqLM,
+ AutoTokenizer,
+ DataCollatorForSeq2Seq,
+ HfArgumentParser,
+ Seq2SeqTrainingArguments,
+ set_seed,
+)
+from transformers.trainer_utils import EvalLoopOutput, EvalPrediction, get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/question-answering/requirements.txt")
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Path to directory to store the pretrained models downloaded from huggingface.co"},
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ context_column: Optional[str] = field(
+ default="context",
+ metadata={"help": "The name of the column in the datasets containing the contexts (for question answering)."},
+ )
+ question_column: Optional[str] = field(
+ default="question",
+ metadata={"help": "The name of the column in the datasets containing the questions (for question answering)."},
+ )
+ answer_column: Optional[str] = field(
+ default="answers",
+ metadata={"help": "The name of the column in the datasets containing the answers (for question answering)."},
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ test_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input test data file to evaluate the perplexity on (a text file)."},
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ max_seq_length: int = field(
+ default=384,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ max_answer_length: int = field(
+ default=30,
+ metadata={
+ "help": (
+ "The maximum length of an answer that can be generated. This is needed because the start "
+ "and end predictions are not conditioned on one another."
+ )
+ },
+ )
+ val_max_answer_length: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The maximum total sequence length for validation target text after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded. Will default to `max_answer_length`. "
+ "This argument is also used to override the ``max_length`` param of ``model.generate``, which is used "
+ "during ``evaluate`` and ``predict``."
+ )
+ },
+ )
+ pad_to_max_length: bool = field(
+ default=True,
+ metadata={
+ "help": (
+ "Whether to pad all samples to `max_seq_length`. If False, will pad the samples dynamically when"
+ " batching to the maximum length in the batch (which can be faster on GPU but will be slower on TPU)."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_predict_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of prediction examples to this "
+ "value if set."
+ )
+ },
+ )
+ version_2_with_negative: bool = field(
+ default=False, metadata={"help": "If true, some of the examples do not have an answer."}
+ )
+ null_score_diff_threshold: float = field(
+ default=0.0,
+ metadata={
+ "help": (
+ "The threshold used to select the null answer: if the best answer has a score that is less than "
+ "the score of the null answer minus this threshold, the null answer is selected for this example. "
+ "Only useful when `version_2_with_negative=True`."
+ )
+ },
+ )
+ doc_stride: int = field(
+ default=128,
+ metadata={"help": "When splitting up a long document into chunks, how much stride to take between chunks."},
+ )
+ n_best_size: int = field(
+ default=20,
+ metadata={"help": "The total number of n-best predictions to generate when looking for an answer."},
+ )
+ num_beams: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Number of beams to use for evaluation. This argument will be passed to ``model.generate``, "
+ "which is used during ``evaluate`` and ``predict``."
+ )
+ },
+ )
+ ignore_pad_token_for_loss: bool = field(
+ default=True,
+ metadata={
+ "help": "Whether to ignore the tokens corresponding to padded labels in the loss computation or not."
+ },
+ )
+
+ def __post_init__(self):
+ if (
+ self.dataset_name is None
+ and self.train_file is None
+ and self.validation_file is None
+ and self.test_file is None
+ ):
+ raise ValueError("Need either a dataset name or a training/validation file/test_file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+ if self.test_file is not None:
+ extension = self.test_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`test_file` should be a csv or a json file."
+ if self.val_max_answer_length is None:
+ self.val_max_answer_length = self.max_answer_length
+
+
+question_answering_column_name_mapping = {
+ "squad_v2": ("question", "context", "answer"),
+}
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, Seq2SeqTrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_seq2seq_qa", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ datasets.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ if data_args.test_file is not None:
+ data_files["test"] = data_args.test_file
+ extension = data_args.test_file.split(".")[-1]
+ raw_datasets = load_dataset(
+ extension,
+ data_files=data_files,
+ field="data",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ model = AutoModelForSeq2SeqLM.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
+ # on a small vocab and want a smaller embedding size, remove this test.
+ embedding_size = model.get_input_embeddings().weight.shape[0]
+ if len(tokenizer) > embedding_size:
+ model.resize_token_embeddings(len(tokenizer))
+
+ if model.config.decoder_start_token_id is None:
+ raise ValueError("Make sure that `config.decoder_start_token_id` is correctly defined")
+
+ # Preprocessing the datasets.
+ # We need to generate and tokenize inputs and targets.
+ if training_args.do_train:
+ column_names = raw_datasets["train"].column_names
+ elif training_args.do_eval:
+ column_names = raw_datasets["validation"].column_names
+ elif training_args.do_predict:
+ column_names = raw_datasets["test"].column_names
+ else:
+ logger.info("There is nothing to do. Please pass `do_train`, `do_eval` and/or `do_predict`.")
+ return
+
+ # Get the column names for input/target.
+ dataset_columns = question_answering_column_name_mapping.get(data_args.dataset_name, None)
+ if data_args.question_column is None:
+ question_column = dataset_columns[0] if dataset_columns is not None else column_names[0]
+ else:
+ question_column = data_args.question_column
+ if question_column not in column_names:
+ raise ValueError(
+ f"--question_column' value '{data_args.question_column}' needs to be one of: {', '.join(column_names)}"
+ )
+ if data_args.context_column is None:
+ context_column = dataset_columns[1] if dataset_columns is not None else column_names[1]
+ else:
+ context_column = data_args.context_column
+ if context_column not in column_names:
+ raise ValueError(
+ f"--context_column' value '{data_args.context_column}' needs to be one of: {', '.join(column_names)}"
+ )
+ if data_args.answer_column is None:
+ answer_column = dataset_columns[2] if dataset_columns is not None else column_names[2]
+ else:
+ answer_column = data_args.answer_column
+ if answer_column not in column_names:
+ raise ValueError(
+ f"--answer_column' value '{data_args.answer_column}' needs to be one of: {', '.join(column_names)}"
+ )
+
+ # Temporarily set max_answer_length for training.
+ max_answer_length = data_args.max_answer_length
+ padding = "max_length" if data_args.pad_to_max_length else False
+
+ if training_args.label_smoothing_factor > 0 and not hasattr(model, "prepare_decoder_input_ids_from_labels"):
+ logger.warning(
+ "label_smoothing is enabled but the `prepare_decoder_input_ids_from_labels` method is not defined for "
+ f"`{model.__class__.__name__}`. This will lead to loss being calculated twice and will take up more memory"
+ )
+
+ if data_args.max_seq_length > tokenizer.model_max_length:
+ logger.warning(
+ f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
+ f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
+ )
+ max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
+
+ def preprocess_squad_batch(
+ examples,
+ question_column: str,
+ context_column: str,
+ answer_column: str,
+ ) -> Tuple[List[str], List[str]]:
+ questions = examples[question_column]
+ contexts = examples[context_column]
+ answers = examples[answer_column]
+
+ def generate_input(_question, _context):
+ return " ".join(["question:", _question.lstrip(), "context:", _context.lstrip()])
+
+ inputs = [generate_input(question, context) for question, context in zip(questions, contexts)]
+ targets = [answer["text"][0] if len(answer["text"]) > 0 else "" for answer in answers]
+ return inputs, targets
+
+ def preprocess_function(examples):
+ inputs, targets = preprocess_squad_batch(examples, question_column, context_column, answer_column)
+
+ model_inputs = tokenizer(inputs, max_length=max_seq_length, padding=padding, truncation=True)
+ # Tokenize targets with text_target=...
+ labels = tokenizer(text_target=targets, max_length=max_answer_length, padding=padding, truncation=True)
+
+ # If we are padding here, replace all tokenizer.pad_token_id in the labels by -100 when we want to ignore
+ # padding in the loss.
+ if padding == "max_length" and data_args.ignore_pad_token_for_loss:
+ labels["input_ids"] = [
+ [(l if l != tokenizer.pad_token_id else -100) for l in label] for label in labels["input_ids"]
+ ]
+
+ model_inputs["labels"] = labels["input_ids"]
+ return model_inputs
+
+ # Validation preprocessing
+ def preprocess_validation_function(examples):
+ inputs, targets = preprocess_squad_batch(examples, question_column, context_column, answer_column)
+
+ model_inputs = tokenizer(
+ inputs,
+ max_length=max_seq_length,
+ padding=padding,
+ truncation=True,
+ return_overflowing_tokens=True,
+ return_offsets_mapping=True,
+ )
+ # Tokenize targets with the `text_target` keyword argument
+ labels = tokenizer(text_target=targets, max_length=max_answer_length, padding=padding, truncation=True)
+
+ # If we are padding here, replace all tokenizer.pad_token_id in the labels by -100 when we want to ignore
+ # padding in the loss.
+ if padding == "max_length" and data_args.ignore_pad_token_for_loss:
+ labels["input_ids"] = [
+ [(l if l != tokenizer.pad_token_id else -100) for l in label] for label in labels["input_ids"]
+ ]
+
+ # Since one example might give us several features if it has a long context, we need a map from a feature to
+ # its corresponding example. This key gives us just that.
+ sample_mapping = model_inputs.pop("overflow_to_sample_mapping")
+
+ # For evaluation, we will need to convert our predictions to substrings of the context, so we keep the
+ # corresponding example_id and we will store the offset mappings.
+ model_inputs["example_id"] = []
+ # Augment the overflowing tokens to the labels
+ labels_out = []
+
+ for i in range(len(model_inputs["input_ids"])):
+ # One example can give several spans, this is the index of the example containing this span of text.
+ sample_index = sample_mapping[i]
+ model_inputs["example_id"].append(examples["id"][sample_index])
+ labels_out.append(labels["input_ids"][sample_index])
+
+ model_inputs["labels"] = labels_out
+ return model_inputs
+
+ if training_args.do_train:
+ if "train" not in raw_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = raw_datasets["train"]
+ if data_args.max_train_samples is not None:
+ # We will select sample from whole data if argument is specified
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+ # Create train feature from dataset
+ with training_args.main_process_first(desc="train dataset map pre-processing"):
+ train_dataset = train_dataset.map(
+ preprocess_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on train dataset",
+ )
+ if data_args.max_train_samples is not None:
+ # Number of samples might increase during Feature Creation, We select only specified max samples
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+
+ if training_args.do_eval:
+ if "validation" not in raw_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_examples = raw_datasets["validation"]
+ if data_args.max_eval_samples is not None:
+ # We will select sample from whole data
+ max_eval_samples = min(len(eval_examples), data_args.max_eval_samples)
+ eval_examples = eval_examples.select(range(max_eval_samples))
+ # Validation Feature Creation
+ with training_args.main_process_first(desc="validation dataset map pre-processing"):
+ eval_dataset = eval_examples.map(
+ preprocess_validation_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on validation dataset",
+ )
+ if data_args.max_eval_samples is not None:
+ # During Feature creation dataset samples might increase, we will select required samples again
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+
+ if training_args.do_predict:
+ if "test" not in raw_datasets:
+ raise ValueError("--do_predict requires a test dataset")
+ predict_examples = raw_datasets["test"]
+ if data_args.max_predict_samples is not None:
+ # We will select sample from whole data
+ predict_examples = predict_examples.select(range(data_args.max_predict_samples))
+ # Predict Feature Creation
+ with training_args.main_process_first(desc="prediction dataset map pre-processing"):
+ predict_dataset = predict_examples.map(
+ preprocess_validation_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on prediction dataset",
+ )
+ if data_args.max_predict_samples is not None:
+ # During Feature creation dataset samples might increase, we will select required samples again
+ max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
+ predict_dataset = predict_dataset.select(range(max_predict_samples))
+
+ # Data collator
+ label_pad_token_id = -100 if data_args.ignore_pad_token_for_loss else tokenizer.pad_token_id
+ data_collator = DataCollatorForSeq2Seq(
+ tokenizer,
+ model=model,
+ label_pad_token_id=label_pad_token_id,
+ pad_to_multiple_of=8 if training_args.fp16 else None,
+ )
+
+ metric = evaluate.load(
+ "squad_v2" if data_args.version_2_with_negative else "squad", cache_dir=model_args.cache_dir
+ )
+
+ def compute_metrics(p: EvalPrediction):
+ return metric.compute(predictions=p.predictions, references=p.label_ids)
+
+ # Post-processing:
+ def post_processing_function(
+ examples: datasets.Dataset, features: datasets.Dataset, outputs: EvalLoopOutput, stage="eval"
+ ):
+ # Decode the predicted tokens.
+ preds = outputs.predictions
+ if isinstance(preds, tuple):
+ preds = preds[0]
+ # Replace -100s used for padding as we can't decode them
+ preds = np.where(preds != -100, preds, tokenizer.pad_token_id)
+ decoded_preds = tokenizer.batch_decode(preds, skip_special_tokens=True)
+
+ # Build a map example to its corresponding features.
+ example_id_to_index = {k: i for i, k in enumerate(examples["id"])}
+ feature_per_example = {example_id_to_index[feature["example_id"]]: i for i, feature in enumerate(features)}
+ predictions = {}
+ # Let's loop over all the examples!
+ for example_index, example in enumerate(examples):
+ # This is the index of the feature associated to the current example.
+ feature_index = feature_per_example[example_index]
+ predictions[example["id"]] = decoded_preds[feature_index]
+
+ # Format the result to the format the metric expects.
+ if data_args.version_2_with_negative:
+ formatted_predictions = [
+ {"id": k, "prediction_text": v, "no_answer_probability": 0.0} for k, v in predictions.items()
+ ]
+ else:
+ formatted_predictions = [{"id": k, "prediction_text": v} for k, v in predictions.items()]
+
+ references = [{"id": ex["id"], "answers": ex[answer_column]} for ex in examples]
+ return EvalPrediction(predictions=formatted_predictions, label_ids=references)
+
+ # Initialize our Trainer
+ trainer = QuestionAnsweringSeq2SeqTrainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset if training_args.do_train else None,
+ eval_dataset=eval_dataset if training_args.do_eval else None,
+ eval_examples=eval_examples if training_args.do_eval else None,
+ processing_class=tokenizer,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics if training_args.predict_with_generate else None,
+ post_process_function=post_processing_function,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model() # Saves the tokenizer too for easy upload
+
+ metrics = train_result.metrics
+ max_train_samples = (
+ data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
+ )
+ metrics["train_samples"] = min(max_train_samples, len(train_dataset))
+
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ results = {}
+ max_length = (
+ training_args.generation_max_length
+ if training_args.generation_max_length is not None
+ else data_args.val_max_answer_length
+ )
+ num_beams = data_args.num_beams if data_args.num_beams is not None else training_args.generation_num_beams
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+ metrics = trainer.evaluate(max_length=max_length, num_beams=num_beams, metric_key_prefix="eval")
+
+ max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
+ metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ # Prediction
+ if training_args.do_predict:
+ logger.info("*** Predict ***")
+ results = trainer.predict(predict_dataset, predict_examples)
+ metrics = results.metrics
+
+ max_predict_samples = (
+ data_args.max_predict_samples if data_args.max_predict_samples is not None else len(predict_dataset)
+ )
+ metrics["predict_samples"] = min(max_predict_samples, len(predict_dataset))
+
+ trainer.log_metrics("predict", metrics)
+ trainer.save_metrics("predict", metrics)
+
+ if training_args.push_to_hub:
+ kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "question-answering"}
+ if data_args.dataset_name is not None:
+ kwargs["dataset_tags"] = data_args.dataset_name
+ if data_args.dataset_config_name is not None:
+ kwargs["dataset_args"] = data_args.dataset_config_name
+ kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
+ else:
+ kwargs["dataset"] = data_args.dataset_name
+
+ trainer.push_to_hub(**kwargs)
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/trainer_qa.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/trainer_qa.py
new file mode 100644
index 0000000000000000000000000000000000000000..10428a2b77e5dd6fff03aabbbbd24fdada6dc2c4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/trainer_qa.py
@@ -0,0 +1,137 @@
+# coding=utf-8
+# Copyright 2020 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+A subclass of `Trainer` specific to Question-Answering tasks
+"""
+
+import math
+import time
+
+from transformers import Trainer, is_torch_xla_available
+from transformers.trainer_utils import PredictionOutput, speed_metrics
+
+
+if is_torch_xla_available():
+ import torch_xla.core.xla_model as xm
+ import torch_xla.debug.metrics as met
+
+
+class QuestionAnsweringTrainer(Trainer):
+ def __init__(self, *args, eval_examples=None, post_process_function=None, **kwargs):
+ super().__init__(*args, **kwargs)
+ self.eval_examples = eval_examples
+ self.post_process_function = post_process_function
+
+ def evaluate(self, eval_dataset=None, eval_examples=None, ignore_keys=None, metric_key_prefix: str = "eval"):
+ eval_dataset = self.eval_dataset if eval_dataset is None else eval_dataset
+ eval_dataloader = self.get_eval_dataloader(eval_dataset)
+ eval_examples = self.eval_examples if eval_examples is None else eval_examples
+
+ # Temporarily disable metric computation, we will do it in the loop here.
+ compute_metrics = self.compute_metrics
+ self.compute_metrics = None
+ eval_loop = self.prediction_loop if self.args.use_legacy_prediction_loop else self.evaluation_loop
+ start_time = time.time()
+ try:
+ output = eval_loop(
+ eval_dataloader,
+ description="Evaluation",
+ # No point gathering the predictions if there are no metrics, otherwise we defer to
+ # self.args.prediction_loss_only
+ prediction_loss_only=True if compute_metrics is None else None,
+ ignore_keys=ignore_keys,
+ metric_key_prefix=metric_key_prefix,
+ )
+ finally:
+ self.compute_metrics = compute_metrics
+ total_batch_size = self.args.eval_batch_size * self.args.world_size
+ if f"{metric_key_prefix}_jit_compilation_time" in output.metrics:
+ start_time += output.metrics[f"{metric_key_prefix}_jit_compilation_time"]
+ output.metrics.update(
+ speed_metrics(
+ metric_key_prefix,
+ start_time,
+ num_samples=output.num_samples,
+ num_steps=math.ceil(output.num_samples / total_batch_size),
+ )
+ )
+ if self.post_process_function is not None and self.compute_metrics is not None and self.args.should_save:
+ # Only the main node write the results by default
+ eval_preds = self.post_process_function(eval_examples, eval_dataset, output.predictions)
+ metrics = self.compute_metrics(eval_preds)
+
+ # Prefix all keys with metric_key_prefix + '_'
+ for key in list(metrics.keys()):
+ if not key.startswith(f"{metric_key_prefix}_"):
+ metrics[f"{metric_key_prefix}_{key}"] = metrics.pop(key)
+ metrics.update(output.metrics)
+ else:
+ metrics = output.metrics
+
+ if self.args.should_log:
+ # Only the main node log the results by default
+ self.log(metrics)
+
+ if self.args.tpu_metrics_debug or self.args.debug:
+ # tpu-comment: Logging debug metrics for PyTorch/XLA (compile, execute times, ops, etc.)
+ xm.master_print(met.metrics_report())
+
+ self.control = self.callback_handler.on_evaluate(self.args, self.state, self.control, metrics)
+ return metrics
+
+ def predict(self, predict_dataset, predict_examples, ignore_keys=None, metric_key_prefix: str = "test"):
+ predict_dataloader = self.get_test_dataloader(predict_dataset)
+
+ # Temporarily disable metric computation, we will do it in the loop here.
+ compute_metrics = self.compute_metrics
+ self.compute_metrics = None
+ eval_loop = self.prediction_loop if self.args.use_legacy_prediction_loop else self.evaluation_loop
+ start_time = time.time()
+ try:
+ output = eval_loop(
+ predict_dataloader,
+ description="Prediction",
+ # No point gathering the predictions if there are no metrics, otherwise we defer to
+ # self.args.prediction_loss_only
+ prediction_loss_only=True if compute_metrics is None else None,
+ ignore_keys=ignore_keys,
+ metric_key_prefix=metric_key_prefix,
+ )
+ finally:
+ self.compute_metrics = compute_metrics
+ total_batch_size = self.args.eval_batch_size * self.args.world_size
+ if f"{metric_key_prefix}_jit_compilation_time" in output.metrics:
+ start_time += output.metrics[f"{metric_key_prefix}_jit_compilation_time"]
+ output.metrics.update(
+ speed_metrics(
+ metric_key_prefix,
+ start_time,
+ num_samples=output.num_samples,
+ num_steps=math.ceil(output.num_samples / total_batch_size),
+ )
+ )
+
+ if self.post_process_function is None or self.compute_metrics is None:
+ return output
+
+ predictions = self.post_process_function(predict_examples, predict_dataset, output.predictions, "predict")
+ metrics = self.compute_metrics(predictions)
+
+ # Prefix all keys with metric_key_prefix + '_'
+ for key in list(metrics.keys()):
+ if not key.startswith(f"{metric_key_prefix}_"):
+ metrics[f"{metric_key_prefix}_{key}"] = metrics.pop(key)
+ metrics.update(output.metrics)
+ return PredictionOutput(predictions=predictions.predictions, label_ids=predictions.label_ids, metrics=metrics)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/trainer_seq2seq_qa.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/trainer_seq2seq_qa.py
new file mode 100644
index 0000000000000000000000000000000000000000..ff9e2d7bc3fe29a0f1b08be368cec0d8b3e8dad6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/trainer_seq2seq_qa.py
@@ -0,0 +1,164 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+A subclass of `Trainer` specific to Question-Answering tasks
+"""
+
+import math
+import time
+from typing import Dict, List, Optional
+
+from torch.utils.data import Dataset
+
+from transformers import Seq2SeqTrainer, is_torch_xla_available
+from transformers.trainer_utils import PredictionOutput, speed_metrics
+
+
+if is_torch_xla_available():
+ import torch_xla.core.xla_model as xm
+ import torch_xla.debug.metrics as met
+
+
+class QuestionAnsweringSeq2SeqTrainer(Seq2SeqTrainer):
+ def __init__(self, *args, eval_examples=None, post_process_function=None, **kwargs):
+ super().__init__(*args, **kwargs)
+ self.eval_examples = eval_examples
+ self.post_process_function = post_process_function
+
+ # def evaluate(self, eval_dataset=None, eval_examples=None, ignore_keys=None, metric_key_prefix: str = "eval"):
+ def evaluate(
+ self,
+ eval_dataset: Optional[Dataset] = None,
+ eval_examples=None,
+ ignore_keys: Optional[List[str]] = None,
+ metric_key_prefix: str = "eval",
+ **gen_kwargs,
+ ) -> Dict[str, float]:
+ gen_kwargs = gen_kwargs.copy()
+
+ # Use legacy argument setting if a) the option is not explicitly passed; and b) the argument is set in the
+ # training args
+ if gen_kwargs.get("max_length") is None and self.args.generation_max_length is not None:
+ gen_kwargs["max_length"] = self.args.generation_max_length
+ if gen_kwargs.get("num_beams") is None and self.args.generation_num_beams is not None:
+ gen_kwargs["num_beams"] = self.args.generation_num_beams
+ self._gen_kwargs = gen_kwargs
+
+ eval_dataset = self.eval_dataset if eval_dataset is None else eval_dataset
+ eval_dataloader = self.get_eval_dataloader(eval_dataset)
+ eval_examples = self.eval_examples if eval_examples is None else eval_examples
+
+ # Temporarily disable metric computation, we will do it in the loop here.
+ compute_metrics = self.compute_metrics
+ self.compute_metrics = None
+ start_time = time.time()
+ eval_loop = self.prediction_loop if self.args.use_legacy_prediction_loop else self.evaluation_loop
+ try:
+ output = eval_loop(
+ eval_dataloader,
+ description="Evaluation",
+ # No point gathering the predictions if there are no metrics, otherwise we defer to
+ # self.args.prediction_loss_only
+ prediction_loss_only=True if compute_metrics is None else None,
+ ignore_keys=ignore_keys,
+ metric_key_prefix=metric_key_prefix,
+ )
+ finally:
+ self.compute_metrics = compute_metrics
+ total_batch_size = self.args.eval_batch_size * self.args.world_size
+ if f"{metric_key_prefix}_jit_compilation_time" in output.metrics:
+ start_time += output.metrics[f"{metric_key_prefix}_jit_compilation_time"]
+ output.metrics.update(
+ speed_metrics(
+ metric_key_prefix,
+ start_time,
+ num_samples=output.num_samples,
+ num_steps=math.ceil(output.num_samples / total_batch_size),
+ )
+ )
+
+ if self.post_process_function is not None and self.compute_metrics is not None and self.args.should_save:
+ # Only the main node write the results by default
+ eval_preds = self.post_process_function(eval_examples, eval_dataset, output)
+ metrics = self.compute_metrics(eval_preds)
+
+ # Prefix all keys with metric_key_prefix + '_'
+ for key in list(metrics.keys()):
+ if not key.startswith(f"{metric_key_prefix}_"):
+ metrics[f"{metric_key_prefix}_{key}"] = metrics.pop(key)
+
+ metrics.update(output.metrics)
+ else:
+ metrics = output.metrics
+
+ if self.args.should_log:
+ # Only the main node log the results by default
+ self.log(metrics)
+
+ if self.args.tpu_metrics_debug or self.args.debug:
+ # tpu-comment: Logging debug metrics for PyTorch/XLA (compile, execute times, ops, etc.)
+ xm.master_print(met.metrics_report())
+
+ self.control = self.callback_handler.on_evaluate(self.args, self.state, self.control, metrics)
+ return metrics
+
+ def predict(
+ self, predict_dataset, predict_examples, ignore_keys=None, metric_key_prefix: str = "test", **gen_kwargs
+ ):
+ self._gen_kwargs = gen_kwargs.copy()
+
+ predict_dataloader = self.get_test_dataloader(predict_dataset)
+
+ # Temporarily disable metric computation, we will do it in the loop here.
+ compute_metrics = self.compute_metrics
+ self.compute_metrics = None
+ start_time = time.time()
+ eval_loop = self.prediction_loop if self.args.use_legacy_prediction_loop else self.evaluation_loop
+ try:
+ output = eval_loop(
+ predict_dataloader,
+ description="Prediction",
+ # No point gathering the predictions if there are no metrics, otherwise we defer to
+ # self.args.prediction_loss_only
+ prediction_loss_only=True if compute_metrics is None else None,
+ ignore_keys=ignore_keys,
+ metric_key_prefix=metric_key_prefix,
+ )
+ finally:
+ self.compute_metrics = compute_metrics
+
+ total_batch_size = self.args.eval_batch_size * self.args.world_size
+ if f"{metric_key_prefix}_jit_compilation_time" in output.metrics:
+ start_time += output.metrics[f"{metric_key_prefix}_jit_compilation_time"]
+ output.metrics.update(
+ speed_metrics(
+ metric_key_prefix,
+ start_time,
+ num_samples=output.num_samples,
+ num_steps=math.ceil(output.num_samples / total_batch_size),
+ )
+ )
+ if self.post_process_function is None or self.compute_metrics is None:
+ return output
+
+ predictions = self.post_process_function(predict_examples, predict_dataset, output, "predict")
+ metrics = self.compute_metrics(predictions)
+
+ # Prefix all keys with metric_key_prefix + '_'
+ for key in list(metrics.keys()):
+ if not key.startswith(f"{metric_key_prefix}_"):
+ metrics[f"{metric_key_prefix}_{key}"] = metrics.pop(key)
+ metrics.update(output.metrics)
+ return PredictionOutput(predictions=predictions.predictions, label_ids=predictions.label_ids, metrics=metrics)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/utils_qa.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/utils_qa.py
new file mode 100644
index 0000000000000000000000000000000000000000..79497dbb816ed2bf3d33e131abecd1aa6caf6027
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/question-answering/utils_qa.py
@@ -0,0 +1,444 @@
+# coding=utf-8
+# Copyright 2020 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Post-processing utilities for question answering.
+"""
+
+import collections
+import json
+import logging
+import os
+from typing import Optional, Tuple
+
+import numpy as np
+from tqdm.auto import tqdm
+
+
+logger = logging.getLogger(__name__)
+
+
+def postprocess_qa_predictions(
+ examples,
+ features,
+ predictions: Tuple[np.ndarray, np.ndarray],
+ version_2_with_negative: bool = False,
+ n_best_size: int = 20,
+ max_answer_length: int = 30,
+ null_score_diff_threshold: float = 0.0,
+ output_dir: Optional[str] = None,
+ prefix: Optional[str] = None,
+ log_level: Optional[int] = logging.WARNING,
+):
+ """
+ Post-processes the predictions of a question-answering model to convert them to answers that are substrings of the
+ original contexts. This is the base postprocessing functions for models that only return start and end logits.
+
+ Args:
+ examples: The non-preprocessed dataset (see the main script for more information).
+ features: The processed dataset (see the main script for more information).
+ predictions (:obj:`Tuple[np.ndarray, np.ndarray]`):
+ The predictions of the model: two arrays containing the start logits and the end logits respectively. Its
+ first dimension must match the number of elements of :obj:`features`.
+ version_2_with_negative (:obj:`bool`, `optional`, defaults to :obj:`False`):
+ Whether or not the underlying dataset contains examples with no answers.
+ n_best_size (:obj:`int`, `optional`, defaults to 20):
+ The total number of n-best predictions to generate when looking for an answer.
+ max_answer_length (:obj:`int`, `optional`, defaults to 30):
+ The maximum length of an answer that can be generated. This is needed because the start and end predictions
+ are not conditioned on one another.
+ null_score_diff_threshold (:obj:`float`, `optional`, defaults to 0):
+ The threshold used to select the null answer: if the best answer has a score that is less than the score of
+ the null answer minus this threshold, the null answer is selected for this example (note that the score of
+ the null answer for an example giving several features is the minimum of the scores for the null answer on
+ each feature: all features must be aligned on the fact they `want` to predict a null answer).
+
+ Only useful when :obj:`version_2_with_negative` is :obj:`True`.
+ output_dir (:obj:`str`, `optional`):
+ If provided, the dictionaries of predictions, n_best predictions (with their scores and logits) and, if
+ :obj:`version_2_with_negative=True`, the dictionary of the scores differences between best and null
+ answers, are saved in `output_dir`.
+ prefix (:obj:`str`, `optional`):
+ If provided, the dictionaries mentioned above are saved with `prefix` added to their names.
+ log_level (:obj:`int`, `optional`, defaults to ``logging.WARNING``):
+ ``logging`` log level (e.g., ``logging.WARNING``)
+ """
+ if len(predictions) != 2:
+ raise ValueError("`predictions` should be a tuple with two elements (start_logits, end_logits).")
+ all_start_logits, all_end_logits = predictions
+
+ if len(predictions[0]) != len(features):
+ raise ValueError(f"Got {len(predictions[0])} predictions and {len(features)} features.")
+
+ # Build a map example to its corresponding features.
+ example_id_to_index = {k: i for i, k in enumerate(examples["id"])}
+ features_per_example = collections.defaultdict(list)
+ for i, feature in enumerate(features):
+ features_per_example[example_id_to_index[feature["example_id"]]].append(i)
+
+ # The dictionaries we have to fill.
+ all_predictions = collections.OrderedDict()
+ all_nbest_json = collections.OrderedDict()
+ if version_2_with_negative:
+ scores_diff_json = collections.OrderedDict()
+
+ # Logging.
+ logger.setLevel(log_level)
+ logger.info(f"Post-processing {len(examples)} example predictions split into {len(features)} features.")
+
+ # Let's loop over all the examples!
+ for example_index, example in enumerate(tqdm(examples)):
+ # Those are the indices of the features associated to the current example.
+ feature_indices = features_per_example[example_index]
+
+ min_null_prediction = None
+ prelim_predictions = []
+
+ # Looping through all the features associated to the current example.
+ for feature_index in feature_indices:
+ # We grab the predictions of the model for this feature.
+ start_logits = all_start_logits[feature_index]
+ end_logits = all_end_logits[feature_index]
+ # This is what will allow us to map some the positions in our logits to span of texts in the original
+ # context.
+ offset_mapping = features[feature_index]["offset_mapping"]
+ # Optional `token_is_max_context`, if provided we will remove answers that do not have the maximum context
+ # available in the current feature.
+ token_is_max_context = features[feature_index].get("token_is_max_context", None)
+
+ # Update minimum null prediction.
+ feature_null_score = start_logits[0] + end_logits[0]
+ if min_null_prediction is None or min_null_prediction["score"] > feature_null_score:
+ min_null_prediction = {
+ "offsets": (0, 0),
+ "score": feature_null_score,
+ "start_logit": start_logits[0],
+ "end_logit": end_logits[0],
+ }
+
+ # Go through all possibilities for the `n_best_size` greater start and end logits.
+ start_indexes = np.argsort(start_logits)[-1 : -n_best_size - 1 : -1].tolist()
+ end_indexes = np.argsort(end_logits)[-1 : -n_best_size - 1 : -1].tolist()
+ for start_index in start_indexes:
+ for end_index in end_indexes:
+ # Don't consider out-of-scope answers, either because the indices are out of bounds or correspond
+ # to part of the input_ids that are not in the context.
+ if (
+ start_index >= len(offset_mapping)
+ or end_index >= len(offset_mapping)
+ or offset_mapping[start_index] is None
+ or len(offset_mapping[start_index]) < 2
+ or offset_mapping[end_index] is None
+ or len(offset_mapping[end_index]) < 2
+ ):
+ continue
+ # Don't consider answers with a length that is either < 0 or > max_answer_length.
+ if end_index < start_index or end_index - start_index + 1 > max_answer_length:
+ continue
+ # Don't consider answer that don't have the maximum context available (if such information is
+ # provided).
+ if token_is_max_context is not None and not token_is_max_context.get(str(start_index), False):
+ continue
+
+ prelim_predictions.append(
+ {
+ "offsets": (offset_mapping[start_index][0], offset_mapping[end_index][1]),
+ "score": start_logits[start_index] + end_logits[end_index],
+ "start_logit": start_logits[start_index],
+ "end_logit": end_logits[end_index],
+ }
+ )
+ if version_2_with_negative and min_null_prediction is not None:
+ # Add the minimum null prediction
+ prelim_predictions.append(min_null_prediction)
+ null_score = min_null_prediction["score"]
+
+ # Only keep the best `n_best_size` predictions.
+ predictions = sorted(prelim_predictions, key=lambda x: x["score"], reverse=True)[:n_best_size]
+
+ # Add back the minimum null prediction if it was removed because of its low score.
+ if (
+ version_2_with_negative
+ and min_null_prediction is not None
+ and not any(p["offsets"] == (0, 0) for p in predictions)
+ ):
+ predictions.append(min_null_prediction)
+
+ # Use the offsets to gather the answer text in the original context.
+ context = example["context"]
+ for pred in predictions:
+ offsets = pred.pop("offsets")
+ pred["text"] = context[offsets[0] : offsets[1]]
+
+ # In the very rare edge case we have not a single non-null prediction, we create a fake prediction to avoid
+ # failure.
+ if len(predictions) == 0 or (len(predictions) == 1 and predictions[0]["text"] == ""):
+ predictions.insert(0, {"text": "empty", "start_logit": 0.0, "end_logit": 0.0, "score": 0.0})
+
+ # Compute the softmax of all scores (we do it with numpy to stay independent from torch/tf in this file, using
+ # the LogSumExp trick).
+ scores = np.array([pred.pop("score") for pred in predictions])
+ exp_scores = np.exp(scores - np.max(scores))
+ probs = exp_scores / exp_scores.sum()
+
+ # Include the probabilities in our predictions.
+ for prob, pred in zip(probs, predictions):
+ pred["probability"] = prob
+
+ # Pick the best prediction. If the null answer is not possible, this is easy.
+ if not version_2_with_negative:
+ all_predictions[example["id"]] = predictions[0]["text"]
+ else:
+ # Otherwise we first need to find the best non-empty prediction.
+ i = 0
+ while predictions[i]["text"] == "":
+ i += 1
+ best_non_null_pred = predictions[i]
+
+ # Then we compare to the null prediction using the threshold.
+ score_diff = null_score - best_non_null_pred["start_logit"] - best_non_null_pred["end_logit"]
+ scores_diff_json[example["id"]] = float(score_diff) # To be JSON-serializable.
+ if score_diff > null_score_diff_threshold:
+ all_predictions[example["id"]] = ""
+ else:
+ all_predictions[example["id"]] = best_non_null_pred["text"]
+
+ # Make `predictions` JSON-serializable by casting np.float back to float.
+ all_nbest_json[example["id"]] = [
+ {k: (float(v) if isinstance(v, (np.float16, np.float32, np.float64)) else v) for k, v in pred.items()}
+ for pred in predictions
+ ]
+
+ # If we have an output_dir, let's save all those dicts.
+ if output_dir is not None:
+ if not os.path.isdir(output_dir):
+ raise EnvironmentError(f"{output_dir} is not a directory.")
+
+ prediction_file = os.path.join(
+ output_dir, "predictions.json" if prefix is None else f"{prefix}_predictions.json"
+ )
+ nbest_file = os.path.join(
+ output_dir, "nbest_predictions.json" if prefix is None else f"{prefix}_nbest_predictions.json"
+ )
+ if version_2_with_negative:
+ null_odds_file = os.path.join(
+ output_dir, "null_odds.json" if prefix is None else f"{prefix}_null_odds.json"
+ )
+
+ logger.info(f"Saving predictions to {prediction_file}.")
+ with open(prediction_file, "w") as writer:
+ writer.write(json.dumps(all_predictions, indent=4) + "\n")
+ logger.info(f"Saving nbest_preds to {nbest_file}.")
+ with open(nbest_file, "w") as writer:
+ writer.write(json.dumps(all_nbest_json, indent=4) + "\n")
+ if version_2_with_negative:
+ logger.info(f"Saving null_odds to {null_odds_file}.")
+ with open(null_odds_file, "w") as writer:
+ writer.write(json.dumps(scores_diff_json, indent=4) + "\n")
+
+ return all_predictions
+
+
+def postprocess_qa_predictions_with_beam_search(
+ examples,
+ features,
+ predictions: Tuple[np.ndarray, np.ndarray],
+ version_2_with_negative: bool = False,
+ n_best_size: int = 20,
+ max_answer_length: int = 30,
+ start_n_top: int = 5,
+ end_n_top: int = 5,
+ output_dir: Optional[str] = None,
+ prefix: Optional[str] = None,
+ log_level: Optional[int] = logging.WARNING,
+):
+ """
+ Post-processes the predictions of a question-answering model with beam search to convert them to answers that are substrings of the
+ original contexts. This is the postprocessing functions for models that return start and end logits, indices, as well as
+ cls token predictions.
+
+ Args:
+ examples: The non-preprocessed dataset (see the main script for more information).
+ features: The processed dataset (see the main script for more information).
+ predictions (:obj:`Tuple[np.ndarray, np.ndarray]`):
+ The predictions of the model: two arrays containing the start logits and the end logits respectively. Its
+ first dimension must match the number of elements of :obj:`features`.
+ version_2_with_negative (:obj:`bool`, `optional`, defaults to :obj:`False`):
+ Whether or not the underlying dataset contains examples with no answers.
+ n_best_size (:obj:`int`, `optional`, defaults to 20):
+ The total number of n-best predictions to generate when looking for an answer.
+ max_answer_length (:obj:`int`, `optional`, defaults to 30):
+ The maximum length of an answer that can be generated. This is needed because the start and end predictions
+ are not conditioned on one another.
+ start_n_top (:obj:`int`, `optional`, defaults to 5):
+ The number of top start logits too keep when searching for the :obj:`n_best_size` predictions.
+ end_n_top (:obj:`int`, `optional`, defaults to 5):
+ The number of top end logits too keep when searching for the :obj:`n_best_size` predictions.
+ output_dir (:obj:`str`, `optional`):
+ If provided, the dictionaries of predictions, n_best predictions (with their scores and logits) and, if
+ :obj:`version_2_with_negative=True`, the dictionary of the scores differences between best and null
+ answers, are saved in `output_dir`.
+ prefix (:obj:`str`, `optional`):
+ If provided, the dictionaries mentioned above are saved with `prefix` added to their names.
+ log_level (:obj:`int`, `optional`, defaults to ``logging.WARNING``):
+ ``logging`` log level (e.g., ``logging.WARNING``)
+ """
+ if len(predictions) != 5:
+ raise ValueError("`predictions` should be a tuple with five elements.")
+ start_top_log_probs, start_top_index, end_top_log_probs, end_top_index, cls_logits = predictions
+
+ if len(predictions[0]) != len(features):
+ raise ValueError(f"Got {len(predictions[0])} predictions and {len(features)} features.")
+
+ # Build a map example to its corresponding features.
+ example_id_to_index = {k: i for i, k in enumerate(examples["id"])}
+ features_per_example = collections.defaultdict(list)
+ for i, feature in enumerate(features):
+ features_per_example[example_id_to_index[feature["example_id"]]].append(i)
+
+ # The dictionaries we have to fill.
+ all_predictions = collections.OrderedDict()
+ all_nbest_json = collections.OrderedDict()
+ scores_diff_json = collections.OrderedDict() if version_2_with_negative else None
+
+ # Logging.
+ logger.setLevel(log_level)
+ logger.info(f"Post-processing {len(examples)} example predictions split into {len(features)} features.")
+
+ # Let's loop over all the examples!
+ for example_index, example in enumerate(tqdm(examples)):
+ # Those are the indices of the features associated to the current example.
+ feature_indices = features_per_example[example_index]
+
+ min_null_score = None
+ prelim_predictions = []
+
+ # Looping through all the features associated to the current example.
+ for feature_index in feature_indices:
+ # We grab the predictions of the model for this feature.
+ start_log_prob = start_top_log_probs[feature_index]
+ start_indexes = start_top_index[feature_index]
+ end_log_prob = end_top_log_probs[feature_index]
+ end_indexes = end_top_index[feature_index]
+ feature_null_score = cls_logits[feature_index]
+ # This is what will allow us to map some the positions in our logits to span of texts in the original
+ # context.
+ offset_mapping = features[feature_index]["offset_mapping"]
+ # Optional `token_is_max_context`, if provided we will remove answers that do not have the maximum context
+ # available in the current feature.
+ token_is_max_context = features[feature_index].get("token_is_max_context", None)
+
+ # Update minimum null prediction
+ if min_null_score is None or feature_null_score < min_null_score:
+ min_null_score = feature_null_score
+
+ # Go through all possibilities for the `n_start_top`/`n_end_top` greater start and end logits.
+ for i in range(start_n_top):
+ for j in range(end_n_top):
+ start_index = int(start_indexes[i])
+ j_index = i * end_n_top + j
+ end_index = int(end_indexes[j_index])
+ # Don't consider out-of-scope answers (last part of the test should be unnecessary because of the
+ # p_mask but let's not take any risk)
+ if (
+ start_index >= len(offset_mapping)
+ or end_index >= len(offset_mapping)
+ or offset_mapping[start_index] is None
+ or len(offset_mapping[start_index]) < 2
+ or offset_mapping[end_index] is None
+ or len(offset_mapping[end_index]) < 2
+ ):
+ continue
+
+ # Don't consider answers with a length negative or > max_answer_length.
+ if end_index < start_index or end_index - start_index + 1 > max_answer_length:
+ continue
+ # Don't consider answer that don't have the maximum context available (if such information is
+ # provided).
+ if token_is_max_context is not None and not token_is_max_context.get(str(start_index), False):
+ continue
+ prelim_predictions.append(
+ {
+ "offsets": (offset_mapping[start_index][0], offset_mapping[end_index][1]),
+ "score": start_log_prob[i] + end_log_prob[j_index],
+ "start_log_prob": start_log_prob[i],
+ "end_log_prob": end_log_prob[j_index],
+ }
+ )
+
+ # Only keep the best `n_best_size` predictions.
+ predictions = sorted(prelim_predictions, key=lambda x: x["score"], reverse=True)[:n_best_size]
+
+ # Use the offsets to gather the answer text in the original context.
+ context = example["context"]
+ for pred in predictions:
+ offsets = pred.pop("offsets")
+ pred["text"] = context[offsets[0] : offsets[1]]
+
+ # In the very rare edge case we have not a single non-null prediction, we create a fake prediction to avoid
+ # failure.
+ if len(predictions) == 0:
+ # Without predictions min_null_score is going to be None and None will cause an exception later
+ min_null_score = -2e-6
+ predictions.insert(0, {"text": "", "start_logit": -1e-6, "end_logit": -1e-6, "score": min_null_score})
+
+ # Compute the softmax of all scores (we do it with numpy to stay independent from torch/tf in this file, using
+ # the LogSumExp trick).
+ scores = np.array([pred.pop("score") for pred in predictions])
+ exp_scores = np.exp(scores - np.max(scores))
+ probs = exp_scores / exp_scores.sum()
+
+ # Include the probabilities in our predictions.
+ for prob, pred in zip(probs, predictions):
+ pred["probability"] = prob
+
+ # Pick the best prediction and set the probability for the null answer.
+ all_predictions[example["id"]] = predictions[0]["text"]
+ if version_2_with_negative:
+ scores_diff_json[example["id"]] = float(min_null_score)
+
+ # Make `predictions` JSON-serializable by casting np.float back to float.
+ all_nbest_json[example["id"]] = [
+ {k: (float(v) if isinstance(v, (np.float16, np.float32, np.float64)) else v) for k, v in pred.items()}
+ for pred in predictions
+ ]
+
+ # If we have an output_dir, let's save all those dicts.
+ if output_dir is not None:
+ if not os.path.isdir(output_dir):
+ raise EnvironmentError(f"{output_dir} is not a directory.")
+
+ prediction_file = os.path.join(
+ output_dir, "predictions.json" if prefix is None else f"{prefix}_predictions.json"
+ )
+ nbest_file = os.path.join(
+ output_dir, "nbest_predictions.json" if prefix is None else f"{prefix}_nbest_predictions.json"
+ )
+ if version_2_with_negative:
+ null_odds_file = os.path.join(
+ output_dir, "null_odds.json" if prefix is None else f"{prefix}_null_odds.json"
+ )
+
+ logger.info(f"Saving predictions to {prediction_file}.")
+ with open(prediction_file, "w") as writer:
+ writer.write(json.dumps(all_predictions, indent=4) + "\n")
+ logger.info(f"Saving nbest_preds to {nbest_file}.")
+ with open(nbest_file, "w") as writer:
+ writer.write(json.dumps(all_nbest_json, indent=4) + "\n")
+ if version_2_with_negative:
+ logger.info(f"Saving null_odds to {null_odds_file}.")
+ with open(null_odds_file, "w") as writer:
+ writer.write(json.dumps(scores_diff_json, indent=4) + "\n")
+
+ return all_predictions, scores_diff_json
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/semantic-segmentation/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/semantic-segmentation/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..287870694c62e9ef687d791ccc2bd883447e9319
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/semantic-segmentation/README.md
@@ -0,0 +1,207 @@
+
+
+# Semantic segmentation examples
+
+This directory contains 2 scripts that showcase how to fine-tune any model supported by the [`AutoModelForSemanticSegmentation` API](https://huggingface.co/docs/transformers/main/en/model_doc/auto#transformers.AutoModelForSemanticSegmentation) (such as [SegFormer](https://huggingface.co/docs/transformers/main/en/model_doc/segformer), [BEiT](https://huggingface.co/docs/transformers/main/en/model_doc/beit), [DPT](https://huggingface.co/docs/transformers/main/en/model_doc/dpt)) using PyTorch.
+
+
+
+Content:
+* [Note on custom data](#note-on-custom-data)
+* [PyTorch version, Trainer](#pytorch-version-trainer)
+* [PyTorch version, no Trainer](#pytorch-version-no-trainer)
+* [Reload and perform inference](#reload-and-perform-inference)
+* [Important notes](#important-notes)
+
+## Note on custom data
+
+In case you'd like to use the script with custom data, there are 2 things required: 1) creating a DatasetDict 2) creating an id2label mapping. Below, these are explained in more detail.
+
+### Creating a `DatasetDict`
+
+The script assumes that you have a `DatasetDict` with 2 columns, "image" and "label", both of type [Image](https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Image). This can be created as follows:
+
+```python
+from datasets import Dataset, DatasetDict, Image
+
+# your images can of course have a different extension
+# semantic segmentation maps are typically stored in the png format
+image_paths_train = ["path/to/image_1.jpg/jpg", "path/to/image_2.jpg/jpg", ..., "path/to/image_n.jpg/jpg"]
+label_paths_train = ["path/to/annotation_1.png", "path/to/annotation_2.png", ..., "path/to/annotation_n.png"]
+
+# same for validation
+# image_paths_validation = [...]
+# label_paths_validation = [...]
+
+def create_dataset(image_paths, label_paths):
+ dataset = Dataset.from_dict({"image": sorted(image_paths),
+ "label": sorted(label_paths)})
+ dataset = dataset.cast_column("image", Image())
+ dataset = dataset.cast_column("label", Image())
+
+ return dataset
+
+# step 1: create Dataset objects
+train_dataset = create_dataset(image_paths_train, label_paths_train)
+validation_dataset = create_dataset(image_paths_validation, label_paths_validation)
+
+# step 2: create DatasetDict
+dataset = DatasetDict({
+ "train": train_dataset,
+ "validation": validation_dataset,
+ }
+)
+
+# step 3: push to hub (assumes you have ran the huggingface-cli login command in a terminal/notebook)
+dataset.push_to_hub("name of repo on the hub")
+
+# optionally, you can push to a private repo on the hub
+# dataset.push_to_hub("name of repo on the hub", private=True)
+```
+
+An example of such a dataset can be seen at [nielsr/ade20k-demo](https://huggingface.co/datasets/nielsr/ade20k-demo).
+
+### Creating an id2label mapping
+
+Besides that, the script also assumes the existence of an `id2label.json` file in the repo, containing a mapping from integers to actual class names. An example of that can be seen [here](https://huggingface.co/datasets/nielsr/ade20k-demo/blob/main/id2label.json). This can be created in Python as follows:
+
+```python
+import json
+# simple example
+id2label = {0: 'cat', 1: 'dog'}
+with open('id2label.json', 'w') as fp:
+ json.dump(id2label, fp)
+```
+
+You can easily upload this by clicking on "Add file" in the "Files and versions" tab of your repo on the hub.
+
+## PyTorch version, Trainer
+
+Based on the script [`run_semantic_segmentation.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/semantic-segmentation/run_semantic_segmentation.py).
+
+The script leverages the [🤗 Trainer API](https://huggingface.co/docs/transformers/main_classes/trainer) to automatically take care of the training for you, running on distributed environments right away.
+
+Here we show how to fine-tune a [SegFormer](https://huggingface.co/nvidia/mit-b0) model on the [segments/sidewalk-semantic](https://huggingface.co/datasets/segments/sidewalk-semantic) dataset:
+
+In order to use `segments/sidewalk-semantic`:
+ - Log in to Hugging Face with `huggingface-cli login` (token can be accessed [here](https://huggingface.co/settings/tokens)).
+ - Accept terms of use for `sidewalk-semantic` on [dataset page](https://huggingface.co/datasets/segments/sidewalk-semantic).
+
+```bash
+python run_semantic_segmentation.py \
+ --model_name_or_path nvidia/mit-b0 \
+ --dataset_name segments/sidewalk-semantic \
+ --output_dir ./segformer_outputs/ \
+ --remove_unused_columns False \
+ --do_train \
+ --do_eval \
+ --push_to_hub \
+ --push_to_hub_model_id segformer-finetuned-sidewalk-10k-steps \
+ --max_steps 10000 \
+ --learning_rate 0.00006 \
+ --lr_scheduler_type polynomial \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 8 \
+ --logging_strategy steps \
+ --logging_steps 100 \
+ --eval_strategy epoch \
+ --save_strategy epoch \
+ --seed 1337
+```
+
+The resulting model can be seen here: https://huggingface.co/nielsr/segformer-finetuned-sidewalk-10k-steps. The corresponding Weights and Biases report [here](https://wandb.ai/nielsrogge/huggingface/reports/SegFormer-fine-tuning--VmlldzoxODY5NTQ2). Note that it's always advised to check the original paper to know the details regarding training hyperparameters. E.g. from the SegFormer paper:
+
+> We trained the models using AdamW optimizer for 160K iterations on ADE20K, Cityscapes, and 80K iterations on COCO-Stuff. (...) We used a batch size of 16 for ADE20K and COCO-Stuff, and a batch size of 8 for Cityscapes. The learning rate was set to an initial value of 0.00006 and then used a “poly” LR schedule with factor 1.0 by default.
+
+Note that you can replace the model and dataset by simply setting the `model_name_or_path` and `dataset_name` arguments respectively, with any model or dataset from the [hub](https://huggingface.co/). For an overview of all possible arguments, we refer to the [docs](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments) of the `TrainingArguments`, which can be passed as flags.
+
+## PyTorch version, no Trainer
+
+Based on the script [`run_semantic_segmentation_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/semantic-segmentation/run_semantic_segmentation.py).
+
+The script leverages [🤗 `Accelerate`](https://github.com/huggingface/accelerate), which allows to write your own training loop in PyTorch, but have it run instantly on any (distributed) environment, including CPU, multi-CPU, GPU, multi-GPU and TPU. It also supports mixed precision.
+
+First, run:
+
+```bash
+accelerate config
+```
+
+and reply to the questions asked regarding the environment on which you'd like to train. Then
+
+```bash
+accelerate test
+```
+
+that will check everything is ready for training. Finally, you can launch training with
+
+```bash
+accelerate launch run_semantic_segmentation_no_trainer.py --output_dir segformer-finetuned-sidewalk --with_tracking --push_to_hub
+```
+
+and boom, you're training, possibly on multiple GPUs, logging everything to all trackers found in your environment (like Weights and Biases, Tensorboard) and regularly pushing your model to the hub (with the repo name being equal to `args.output_dir` at your HF username) 🤗
+
+With the default settings, the script fine-tunes a [SegFormer]((https://huggingface.co/docs/transformers/main/en/model_doc/segformer)) model on the [segments/sidewalk-semantic](https://huggingface.co/datasets/segments/sidewalk-semantic) dataset.
+
+The resulting model can be seen here: https://huggingface.co/nielsr/segformer-finetuned-sidewalk. Note that the script usually requires quite a few epochs to achieve great results, e.g. the SegFormer authors fine-tuned their model for 160k steps (batches) on [`scene_parse_150`](https://huggingface.co/datasets/scene_parse_150).
+
+## Reload and perform inference
+
+This means that after training, you can easily load your trained model as follows:
+
+```python
+from transformers import AutoImageProcessor, AutoModelForSemanticSegmentation
+
+model_name = "name_of_repo_on_the_hub_or_path_to_local_folder"
+
+image_processor = AutoImageProcessor.from_pretrained(model_name)
+model = AutoModelForSemanticSegmentation.from_pretrained(model_name)
+```
+
+and perform inference as follows:
+
+```python
+from PIL import Image
+import requests
+import torch
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+# prepare image for the model
+inputs = image_processor(images=image, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs)
+ logits = outputs.logits
+
+# rescale logits to original image size
+logits = nn.functional.interpolate(outputs.logits.detach().cpu(),
+ size=image.size[::-1], # (height, width)
+ mode='bilinear',
+ align_corners=False)
+
+predicted = logits.argmax(1)
+```
+
+For visualization of the segmentation maps, we refer to the [example notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/SegFormer/Segformer_inference_notebook.ipynb).
+
+## Important notes
+
+Some datasets, like [`scene_parse_150`](https://huggingface.co/datasets/scene_parse_150), contain a "background" label that is not part of the classes. The Scene Parse 150 dataset for instance contains labels between 0 and 150, with 0 being the background class, and 1 to 150 being actual class names (like "tree", "person", etc.). For these kind of datasets, one replaces the background label (0) by 255, which is the `ignore_index` of the PyTorch model's loss function, and reduces all labels by 1. This way, the `labels` are PyTorch tensors containing values between 0 and 149, and 255 for all background/padding.
+
+In case you're training on such a dataset, make sure to set the ``do_reduce_labels`` flag, which will take care of this.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/semantic-segmentation/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/semantic-segmentation/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..7d62aa141db38399fcc633133fdf537f61ba1f30
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/semantic-segmentation/requirements.txt
@@ -0,0 +1,6 @@
+datasets >= 2.0.0
+torch >= 1.3
+accelerate
+evaluate
+Pillow
+albumentations >= 1.4.16
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/semantic-segmentation/run_semantic_segmentation.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/semantic-segmentation/run_semantic_segmentation.py
new file mode 100644
index 0000000000000000000000000000000000000000..0551b5f61f10c5d7ff7eac0c74960031d1892de3
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/semantic-segmentation/run_semantic_segmentation.py
@@ -0,0 +1,442 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+
+import json
+import logging
+import os
+import sys
+import warnings
+from dataclasses import dataclass, field
+from functools import partial
+from typing import Optional
+
+import albumentations as A
+import evaluate
+import numpy as np
+import torch
+from albumentations.pytorch import ToTensorV2
+from datasets import load_dataset
+from huggingface_hub import hf_hub_download
+from torch import nn
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoImageProcessor,
+ AutoModelForSemanticSegmentation,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ default_data_collator,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+""" Finetuning any 🤗 Transformers model supported by AutoModelForSemanticSegmentation for semantic segmentation leveraging the Trainer API."""
+
+logger = logging.getLogger(__name__)
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=2.0.0", "To fix: pip install -r examples/pytorch/semantic-segmentation/requirements.txt")
+
+
+def reduce_labels_transform(labels: np.ndarray, **kwargs) -> np.ndarray:
+ """Set `0` label as with value 255 and then reduce all other labels by 1.
+
+ Example:
+ Initial class labels: 0 - background; 1 - road; 2 - car;
+ Transformed class labels: 255 - background; 0 - road; 1 - car;
+
+ **kwargs are required to use this function with albumentations.
+ """
+ labels[labels == 0] = 255
+ labels = labels - 1
+ labels[labels == 254] = 255
+ return labels
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ Using `HfArgumentParser` we can turn this class into argparse arguments to be able to specify
+ them on the command line.
+ """
+
+ dataset_name: Optional[str] = field(
+ default="segments/sidewalk-semantic",
+ metadata={
+ "help": "Name of a dataset from the hub (could be your own, possibly private dataset hosted on the hub)."
+ },
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_val_split: Optional[float] = field(
+ default=0.15, metadata={"help": "Percent to split off of train for validation."}
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ do_reduce_labels: Optional[bool] = field(
+ default=False,
+ metadata={"help": "Whether or not to reduce all labels by 1 and replace background by 255."},
+ )
+ reduce_labels: Optional[bool] = field(
+ default=False,
+ metadata={"help": "Whether or not to reduce all labels by 1 and replace background by 255."},
+ )
+
+ def __post_init__(self):
+ if self.dataset_name is None and (self.train_dir is None and self.validation_dir is None):
+ raise ValueError(
+ "You must specify either a dataset name from the hub or a train and/or validation directory."
+ )
+ if self.reduce_labels:
+ self.do_reduce_labels = self.reduce_labels
+ warnings.warn(
+ "The `reduce_labels` argument is deprecated and will be removed in v4.45. Please use `do_reduce_labels` instead.",
+ FutureWarning,
+ )
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ default="nvidia/mit-b0",
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"},
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ image_processor_name: str = field(default=None, metadata={"help": "Name or path of preprocessor config."})
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_semantic_segmentation", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Load dataset
+ # In distributed training, the load_dataset function guarantees that only one local process can concurrently
+ # download the dataset.
+ # TODO support datasets from local folders
+ dataset = load_dataset(
+ data_args.dataset_name, cache_dir=model_args.cache_dir, trust_remote_code=model_args.trust_remote_code
+ )
+
+ # Rename column names to standardized names (only "image" and "label" need to be present)
+ if "pixel_values" in dataset["train"].column_names:
+ dataset = dataset.rename_columns({"pixel_values": "image"})
+ if "annotation" in dataset["train"].column_names:
+ dataset = dataset.rename_columns({"annotation": "label"})
+
+ # If we don't have a validation split, split off a percentage of train as validation.
+ data_args.train_val_split = None if "validation" in dataset.keys() else data_args.train_val_split
+ if isinstance(data_args.train_val_split, float) and data_args.train_val_split > 0.0:
+ split = dataset["train"].train_test_split(data_args.train_val_split)
+ dataset["train"] = split["train"]
+ dataset["validation"] = split["test"]
+
+ # Prepare label mappings.
+ # We'll include these in the model's config to get human readable labels in the Inference API.
+ if data_args.dataset_name == "scene_parse_150":
+ repo_id = "huggingface/label-files"
+ filename = "ade20k-id2label.json"
+ else:
+ repo_id = data_args.dataset_name
+ filename = "id2label.json"
+ id2label = json.load(open(hf_hub_download(repo_id, filename, repo_type="dataset"), "r"))
+ id2label = {int(k): v for k, v in id2label.items()}
+ label2id = {v: str(k) for k, v in id2label.items()}
+
+ # Load the mean IoU metric from the evaluate package
+ metric = evaluate.load("mean_iou", cache_dir=model_args.cache_dir)
+
+ # Define our compute_metrics function. It takes an `EvalPrediction` object (a namedtuple with a
+ # predictions and label_ids field) and has to return a dictionary string to float.
+ @torch.no_grad()
+ def compute_metrics(eval_pred):
+ logits, labels = eval_pred
+ logits_tensor = torch.from_numpy(logits)
+ # scale the logits to the size of the label
+ logits_tensor = nn.functional.interpolate(
+ logits_tensor,
+ size=labels.shape[-2:],
+ mode="bilinear",
+ align_corners=False,
+ ).argmax(dim=1)
+
+ pred_labels = logits_tensor.detach().cpu().numpy()
+ metrics = metric.compute(
+ predictions=pred_labels,
+ references=labels,
+ num_labels=len(id2label),
+ ignore_index=0,
+ reduce_labels=image_processor.do_reduce_labels,
+ )
+ # add per category metrics as individual key-value pairs
+ per_category_accuracy = metrics.pop("per_category_accuracy").tolist()
+ per_category_iou = metrics.pop("per_category_iou").tolist()
+
+ metrics.update({f"accuracy_{id2label[i]}": v for i, v in enumerate(per_category_accuracy)})
+ metrics.update({f"iou_{id2label[i]}": v for i, v in enumerate(per_category_iou)})
+
+ return metrics
+
+ config = AutoConfig.from_pretrained(
+ model_args.config_name or model_args.model_name_or_path,
+ label2id=label2id,
+ id2label=id2label,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ model = AutoModelForSemanticSegmentation.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ image_processor = AutoImageProcessor.from_pretrained(
+ model_args.image_processor_name or model_args.model_name_or_path,
+ do_reduce_labels=data_args.do_reduce_labels,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ # Define transforms to be applied to each image and target.
+ if "shortest_edge" in image_processor.size:
+ # We instead set the target size as (shortest_edge, shortest_edge) to here to ensure all images are batchable.
+ height, width = image_processor.size["shortest_edge"], image_processor.size["shortest_edge"]
+ else:
+ height, width = image_processor.size["height"], image_processor.size["width"]
+ train_transforms = A.Compose(
+ [
+ A.Lambda(
+ name="reduce_labels",
+ mask=reduce_labels_transform if data_args.do_reduce_labels else None,
+ p=1.0,
+ ),
+ # pad image with 255, because it is ignored by loss
+ A.PadIfNeeded(min_height=height, min_width=width, border_mode=0, value=255, p=1.0),
+ A.RandomCrop(height=height, width=width, p=1.0),
+ A.HorizontalFlip(p=0.5),
+ A.Normalize(mean=image_processor.image_mean, std=image_processor.image_std, max_pixel_value=255.0, p=1.0),
+ ToTensorV2(),
+ ]
+ )
+ val_transforms = A.Compose(
+ [
+ A.Lambda(
+ name="reduce_labels",
+ mask=reduce_labels_transform if data_args.do_reduce_labels else None,
+ p=1.0,
+ ),
+ A.Resize(height=height, width=width, p=1.0),
+ A.Normalize(mean=image_processor.image_mean, std=image_processor.image_std, max_pixel_value=255.0, p=1.0),
+ ToTensorV2(),
+ ]
+ )
+
+ def preprocess_batch(example_batch, transforms: A.Compose):
+ pixel_values = []
+ labels = []
+ for image, target in zip(example_batch["image"], example_batch["label"]):
+ transformed = transforms(image=np.array(image.convert("RGB")), mask=np.array(target))
+ pixel_values.append(transformed["image"])
+ labels.append(transformed["mask"])
+
+ encoding = {}
+ encoding["pixel_values"] = torch.stack(pixel_values).to(torch.float)
+ encoding["labels"] = torch.stack(labels).to(torch.long)
+
+ return encoding
+
+ # Preprocess function for dataset should have only one argument,
+ # so we use partial to pass the transforms
+ preprocess_train_batch_fn = partial(preprocess_batch, transforms=train_transforms)
+ preprocess_val_batch_fn = partial(preprocess_batch, transforms=val_transforms)
+
+ if training_args.do_train:
+ if "train" not in dataset:
+ raise ValueError("--do_train requires a train dataset")
+ if data_args.max_train_samples is not None:
+ dataset["train"] = (
+ dataset["train"].shuffle(seed=training_args.seed).select(range(data_args.max_train_samples))
+ )
+ # Set the training transforms
+ dataset["train"].set_transform(preprocess_train_batch_fn)
+
+ if training_args.do_eval:
+ if "validation" not in dataset:
+ raise ValueError("--do_eval requires a validation dataset")
+ if data_args.max_eval_samples is not None:
+ dataset["validation"] = (
+ dataset["validation"].shuffle(seed=training_args.seed).select(range(data_args.max_eval_samples))
+ )
+ # Set the validation transforms
+ dataset["validation"].set_transform(preprocess_val_batch_fn)
+
+ # Initialize our trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=dataset["train"] if training_args.do_train else None,
+ eval_dataset=dataset["validation"] if training_args.do_eval else None,
+ compute_metrics=compute_metrics,
+ processing_class=image_processor,
+ data_collator=default_data_collator,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model()
+ trainer.log_metrics("train", train_result.metrics)
+ trainer.save_metrics("train", train_result.metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ metrics = trainer.evaluate()
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ # Write model card and (optionally) push to hub
+ kwargs = {
+ "finetuned_from": model_args.model_name_or_path,
+ "dataset": data_args.dataset_name,
+ "tags": ["image-segmentation", "vision"],
+ }
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/semantic-segmentation/run_semantic_segmentation_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/semantic-segmentation/run_semantic_segmentation_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..8a0d9de748f9ecc415d083a94958662645c99d13
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/semantic-segmentation/run_semantic_segmentation_no_trainer.py
@@ -0,0 +1,634 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Finetuning any 🤗 Transformers model supported by AutoModelForSemanticSegmentation for semantic segmentation."""
+
+import argparse
+import json
+import math
+import os
+import warnings
+from functools import partial
+from pathlib import Path
+
+import albumentations as A
+import datasets
+import evaluate
+import numpy as np
+import torch
+from accelerate import Accelerator
+from accelerate.logging import get_logger
+from accelerate.utils import set_seed
+from albumentations.pytorch import ToTensorV2
+from datasets import load_dataset
+from huggingface_hub import HfApi, hf_hub_download
+from torch.utils.data import DataLoader
+from tqdm.auto import tqdm
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoImageProcessor,
+ AutoModelForSemanticSegmentation,
+ SchedulerType,
+ default_data_collator,
+ get_scheduler,
+)
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+logger = get_logger(__name__)
+
+require_version("datasets>=2.0.0", "To fix: pip install -r examples/pytorch/semantic-segmentation/requirements.txt")
+
+
+def reduce_labels_transform(labels: np.ndarray, **kwargs) -> np.ndarray:
+ """Set `0` label as with value 255 and then reduce all other labels by 1.
+
+ Example:
+ Initial class labels: 0 - background; 1 - road; 2 - car;
+ Transformed class labels: 255 - background; 0 - road; 1 - car;
+
+ **kwargs are required to use this function with albumentations.
+ """
+ labels[labels == 0] = 255
+ labels = labels - 1
+ labels[labels == 254] = 255
+ return labels
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Finetune a transformers model on a image semantic segmentation task")
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to a pretrained model or model identifier from huggingface.co/models.",
+ default="nvidia/mit-b0",
+ )
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ help="Name of the dataset on the hub.",
+ default="segments/sidewalk-semantic",
+ )
+ parser.add_argument(
+ "--do_reduce_labels",
+ action="store_true",
+ help="Whether or not to reduce all labels by 1 and replace background by 255.",
+ )
+ parser.add_argument(
+ "--reduce_labels",
+ action="store_true",
+ help="Whether or not to reduce all labels by 1 and replace background by 255.",
+ )
+ parser.add_argument(
+ "--train_val_split",
+ type=float,
+ default=0.15,
+ help="Fraction of the dataset to be used for validation.",
+ )
+ parser.add_argument(
+ "--cache_dir",
+ type=str,
+ help="Path to a folder in which the model and dataset will be cached.",
+ )
+ parser.add_argument(
+ "--use_auth_token",
+ action="store_true",
+ help="Whether to use an authentication token to access the model repository.",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument(
+ "--adam_beta1",
+ type=float,
+ default=0.9,
+ help="Beta1 for AdamW optimizer",
+ )
+ parser.add_argument(
+ "--adam_beta2",
+ type=float,
+ default=0.999,
+ help="Beta2 for AdamW optimizer",
+ )
+ parser.add_argument(
+ "--adam_epsilon",
+ type=float,
+ default=1e-8,
+ help="Epsilon for AdamW optimizer",
+ )
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="polynomial",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--trust_remote_code",
+ action="store_true",
+ help=(
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ required=False,
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+ if args.push_to_hub or args.with_tracking:
+ if args.output_dir is None:
+ raise ValueError(
+ "Need an `output_dir` to create a repo when `--push_to_hub` or `with_tracking` is specified."
+ )
+
+ # Deprecation
+ if args.reduce_labels:
+ args.do_reduce_labels = args.reduce_labels
+ warnings.warn(
+ "The `reduce_labels` argument is deprecated and will be removed in v4.45. Please use `do_reduce_labels` instead.",
+ FutureWarning,
+ )
+
+ if args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+
+ return args
+
+
+def main():
+ args = parse_args()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_semantic_segmentation_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+ accelerator_log_kwargs = {}
+
+ if args.with_tracking:
+ accelerator_log_kwargs["log_with"] = args.report_to
+ accelerator_log_kwargs["project_dir"] = args.output_dir
+
+ accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
+
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ # We set device_specific to True as we want different data augmentation per device.
+ if args.seed is not None:
+ set_seed(args.seed, device_specific=True)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Load dataset
+ # In distributed training, the load_dataset function guarantees that only one local process can concurrently
+ # download the dataset.
+ # TODO support datasets from local folders
+ dataset = load_dataset(args.dataset_name, cache_dir=args.cache_dir, trust_remote_code=args.trust_remote_code)
+
+ # Rename column names to standardized names (only "image" and "label" need to be present)
+ if "pixel_values" in dataset["train"].column_names:
+ dataset = dataset.rename_columns({"pixel_values": "image"})
+ if "annotation" in dataset["train"].column_names:
+ dataset = dataset.rename_columns({"annotation": "label"})
+
+ # If we don't have a validation split, split off a percentage of train as validation.
+ args.train_val_split = None if "validation" in dataset.keys() else args.train_val_split
+ if isinstance(args.train_val_split, float) and args.train_val_split > 0.0:
+ split = dataset["train"].train_test_split(args.train_val_split)
+ dataset["train"] = split["train"]
+ dataset["validation"] = split["test"]
+
+ # Prepare label mappings.
+ # We'll include these in the model's config to get human readable labels in the Inference API.
+ if args.dataset_name == "scene_parse_150":
+ repo_id = "huggingface/label-files"
+ filename = "ade20k-id2label.json"
+ else:
+ repo_id = args.dataset_name
+ filename = "id2label.json"
+ id2label = json.load(open(hf_hub_download(repo_id, filename, repo_type="dataset"), "r"))
+ id2label = {int(k): v for k, v in id2label.items()}
+ label2id = {v: k for k, v in id2label.items()}
+
+ # Load pretrained model and image processor
+ config = AutoConfig.from_pretrained(
+ args.model_name_or_path, id2label=id2label, label2id=label2id, trust_remote_code=args.trust_remote_code
+ )
+ image_processor = AutoImageProcessor.from_pretrained(
+ args.model_name_or_path, trust_remote_code=args.trust_remote_code
+ )
+ model = AutoModelForSemanticSegmentation.from_pretrained(
+ args.model_name_or_path,
+ config=config,
+ trust_remote_code=args.trust_remote_code,
+ do_reduce_labels=args.do_reduce_labels,
+ )
+
+ # Define transforms to be applied to each image and target.
+ if "shortest_edge" in image_processor.size:
+ # We instead set the target size as (shortest_edge, shortest_edge) to here to ensure all images are batchable.
+ height, width = image_processor.size["shortest_edge"], image_processor.size["shortest_edge"]
+ else:
+ height, width = image_processor.size["height"], image_processor.size["width"]
+ train_transforms = A.Compose(
+ [
+ A.Lambda(name="reduce_labels", mask=reduce_labels_transform if args.do_reduce_labels else None, p=1.0),
+ # pad image with 255, because it is ignored by loss
+ A.PadIfNeeded(min_height=height, min_width=width, border_mode=0, value=255, p=1.0),
+ A.RandomCrop(height=height, width=width, p=1.0),
+ A.HorizontalFlip(p=0.5),
+ A.Normalize(mean=image_processor.image_mean, std=image_processor.image_std, max_pixel_value=255.0, p=1.0),
+ ToTensorV2(),
+ ]
+ )
+ val_transforms = A.Compose(
+ [
+ A.Lambda(name="reduce_labels", mask=reduce_labels_transform if args.do_reduce_labels else None, p=1.0),
+ A.Resize(height=height, width=width, p=1.0),
+ A.Normalize(mean=image_processor.image_mean, std=image_processor.image_std, max_pixel_value=255.0, p=1.0),
+ ToTensorV2(),
+ ]
+ )
+
+ def preprocess_batch(example_batch, transforms: A.Compose):
+ pixel_values = []
+ labels = []
+ for image, target in zip(example_batch["image"], example_batch["label"]):
+ transformed = transforms(image=np.array(image.convert("RGB")), mask=np.array(target))
+ pixel_values.append(transformed["image"])
+ labels.append(transformed["mask"])
+
+ encoding = {}
+ encoding["pixel_values"] = torch.stack(pixel_values).to(torch.float)
+ encoding["labels"] = torch.stack(labels).to(torch.long)
+
+ return encoding
+
+ # Preprocess function for dataset should have only one input argument,
+ # so we use partial to pass transforms
+ preprocess_train_batch_fn = partial(preprocess_batch, transforms=train_transforms)
+ preprocess_val_batch_fn = partial(preprocess_batch, transforms=val_transforms)
+
+ with accelerator.main_process_first():
+ train_dataset = dataset["train"].with_transform(preprocess_train_batch_fn)
+ eval_dataset = dataset["validation"].with_transform(preprocess_val_batch_fn)
+
+ train_dataloader = DataLoader(
+ train_dataset, shuffle=True, collate_fn=default_data_collator, batch_size=args.per_device_train_batch_size
+ )
+ eval_dataloader = DataLoader(
+ eval_dataset, collate_fn=default_data_collator, batch_size=args.per_device_eval_batch_size
+ )
+
+ # Optimizer
+ optimizer = torch.optim.AdamW(
+ list(model.parameters()),
+ lr=args.learning_rate,
+ betas=[args.adam_beta1, args.adam_beta2],
+ eps=args.adam_epsilon,
+ )
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
+ num_training_steps=args.max_train_steps
+ if overrode_max_train_steps
+ else args.max_train_steps * accelerator.num_processes,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # Instantiate metric
+ metric = evaluate.load("mean_iou", cache_dir=args.cache_dir)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("semantic_segmentation_no_trainer", experiment_config)
+
+ # Train!
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ checkpoint_path = args.resume_from_checkpoint
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ checkpoint_path = path
+ path = os.path.basename(checkpoint_path)
+
+ accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
+ accelerator.load_state(checkpoint_path)
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ completed_steps = resume_step // args.gradient_accumulation_steps
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We skip the first `n` batches in the dataloader when resuming from a checkpoint
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ with accelerator.accumulate(model):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # Checks if the accelerator has performed an optimization step behind the scenes
+ if accelerator.sync_gradients:
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir,
+ is_main_process=accelerator.is_main_process,
+ save_function=accelerator.save,
+ )
+ if accelerator.is_main_process:
+ image_processor.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if completed_steps >= args.max_train_steps:
+ break
+
+ logger.info("***** Running evaluation *****")
+ model.eval()
+ for step, batch in enumerate(tqdm(eval_dataloader, disable=not accelerator.is_local_main_process)):
+ with torch.no_grad():
+ outputs = model(**batch)
+
+ upsampled_logits = torch.nn.functional.interpolate(
+ outputs.logits, size=batch["labels"].shape[-2:], mode="bilinear", align_corners=False
+ )
+ predictions = upsampled_logits.argmax(dim=1)
+
+ predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
+
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metrics = metric.compute(
+ num_labels=len(id2label),
+ ignore_index=255,
+ reduce_labels=False, # we've already reduced the labels before
+ )
+ logger.info(f"epoch {epoch}: {eval_metrics}")
+
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "mean_iou": eval_metrics["mean_iou"],
+ "mean_accuracy": eval_metrics["mean_accuracy"],
+ "overall_accuracy": eval_metrics["overall_accuracy"],
+ "train_loss": total_loss.item() / len(train_dataloader),
+ "epoch": epoch,
+ "step": completed_steps,
+ },
+ step=completed_steps,
+ )
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ image_processor.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if args.checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.with_tracking:
+ accelerator.end_training()
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ image_processor.save_pretrained(args.output_dir)
+ if args.push_to_hub:
+ api.upload_folder(
+ commit_message="End of training",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ all_results = {
+ f"eval_{k}": v.tolist() if isinstance(v, np.ndarray) else v for k, v in eval_metrics.items()
+ }
+ with open(os.path.join(args.output_dir, "all_results.json"), "w") as f:
+ json.dump(all_results, f, indent=2)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-pretraining/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-pretraining/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..d0126634d2310a7cdaf5fe0bc08b6ac46d845e77
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-pretraining/README.md
@@ -0,0 +1,161 @@
+
+
+# Speech Recognition Pre-Training
+
+
+## Wav2Vec2 Speech Pre-Training
+
+The script [`run_speech_wav2vec2_pretraining_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/speech-pretraining/run_wav2vec2_pretraining_no_trainer.py) can be used to pre-train a [Wav2Vec2](https://huggingface.co/transformers/model_doc/wav2vec2.html?highlight=wav2vec2) model from scratch.
+
+In the script [`run_speech_wav2vec2_pretraining_no_trainer`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/speech-pretraining/run_wav2vec2_pretraining_no_trainer.py), a Wav2Vec2 model is pre-trained on audio data alone using [Wav2Vec2's contrastive loss objective](https://arxiv.org/abs/2006.11477).
+
+The following examples show how to fine-tune a `"base"`-sized Wav2Vec2 model as well as a `"large"`-sized Wav2Vec2 model using [`accelerate`](https://github.com/huggingface/accelerate).
+
+
+---
+**NOTE 1**
+
+Wav2Vec2's pre-training is known to be quite unstable.
+It is advised to do a couple of test runs with a smaller dataset,
+*i.e.* `--dataset_config_names clean clean`, `--dataset_split_names validation test`
+to find good hyper-parameters for `learning_rate`, `batch_size`, `num_warmup_steps`,
+and the optimizer.
+A good metric to observe during training is the gradient norm which should ideally be between 0.5 and 2.
+
+---
+
+---
+**NOTE 2**
+
+When training a model on large datasets it is recommended to run the data preprocessing
+in a first run in a **non-distributed** mode via `--preprocessing_only` so that
+when running the model in **distributed** mode in a second step the preprocessed data
+can easily be loaded on each distributed device.
+
+---
+
+### Demo
+
+In this demo run we pre-train a `"base-sized"` Wav2Vec2 model simply only on the validation
+and test data of [librispeech_asr](https://huggingface.co/datasets/librispeech_asr).
+
+The demo is run on two Titan RTX (24 GB RAM each). In case you have less RAM available
+per device, consider reducing `--batch_size` and/or the `--max_duration_in_seconds`.
+
+
+```bash
+accelerate launch run_wav2vec2_pretraining_no_trainer.py \
+ --dataset_name="librispeech_asr" \
+ --dataset_config_names clean clean \
+ --dataset_split_names validation test \
+ --model_name_or_path="patrickvonplaten/wav2vec2-base-v2" \
+ --output_dir="./wav2vec2-pretrained-demo" \
+ --max_train_steps="20000" \
+ --num_warmup_steps="32000" \
+ --gradient_accumulation_steps="8" \
+ --learning_rate="0.005" \
+ --weight_decay="0.01" \
+ --max_duration_in_seconds="20.0" \
+ --min_duration_in_seconds="2.0" \
+ --logging_steps="1" \
+ --saving_steps="10000" \
+ --per_device_train_batch_size="8" \
+ --per_device_eval_batch_size="8" \
+ --adam_beta1="0.9" \
+ --adam_beta2="0.98" \
+ --adam_epsilon="1e-06" \
+ --gradient_checkpointing \
+ --mask_time_prob="0.65" \
+ --mask_time_length="10"
+```
+
+The results of this run can be seen [here](https://wandb.ai/patrickvonplaten/wav2vec2-pretrained-demo/reports/Wav2Vec2-PreTraining-Demo-Run--VmlldzoxMDk3MjAw?accessToken=oa05s1y57lizo2ocxy3k01g6db1u4pt8m6ur2n8nl4cb0ug02ms2cw313kb8ruch).
+
+### Base
+
+To pre-train `"base-sized"` Wav2Vec2 model, *e.g.* [facebook/wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base)
+on [librispeech_asr](https://huggingface.co/datasets/librispeech_asr), the following command can be run:
+
+```bash
+accelerate launch run_wav2vec2_pretraining_no_trainer.py \
+ --dataset_name=librispeech_asr \
+ --dataset_config_names clean clean other \
+ --dataset_split_names train.100 train.360 train.500 \
+ --model_name_or_path="patrickvonplaten/wav2vec2-base-v2" \
+ --output_dir="./wav2vec2-pretrained-demo" \
+ --max_train_steps="200000" \
+ --num_warmup_steps="32000" \
+ --gradient_accumulation_steps="4" \
+ --learning_rate="0.001" \
+ --weight_decay="0.01" \
+ --max_duration_in_seconds="20.0" \
+ --min_duration_in_seconds="2.0" \
+ --logging_steps="1" \
+ --saving_steps="10000" \
+ --per_device_train_batch_size="8" \
+ --per_device_eval_batch_size="8" \
+ --adam_beta1="0.9" \
+ --adam_beta2="0.98" \
+ --adam_epsilon="1e-06" \
+ --gradient_checkpointing \
+ --mask_time_prob="0.65" \
+ --mask_time_length="10"
+```
+
+The experiment was run on 8 GPU V100 (16 GB RAM each) for 4 days.
+In case you have more than 8 GPUs available for a higher effective `batch_size`,
+it is recommended to increase the `learning_rate` to `0.005` for faster convergence.
+
+The results of this run can be seen [here](https://wandb.ai/patrickvonplaten/test/reports/Wav2Vec2-Base--VmlldzoxMTUyODQ0?accessToken=rg6e8u9yizx964k8q47zctq1m4afpvtn1i3qi9exgdmzip6xwkfzvagfajpzj55n) and the checkpoint pretrained for 85,000 steps can be accessed [here](https://huggingface.co/patrickvonplaten/wav2vec2-base-repro-960h-libri-85k-steps)
+
+
+### Large
+
+To pre-train `"large-sized"` Wav2Vec2 model, *e.g.* [facebook/wav2vec2-large-lv60](https://huggingface.co/facebook/wav2vec2-large-lv60),
+on [librispeech_asr](https://huggingface.co/datasets/librispeech_asr), the following command can be run:
+
+```bash
+accelerate launch run_wav2vec2_pretraining_no_trainer.py \
+ --dataset_name=librispeech_asr \
+ --dataset_config_names clean clean other \
+ --dataset_split_names train.100 train.360 train.500 \
+ --output_dir=./test \
+ --max_train_steps=200000 \
+ --num_warmup_steps=32000 \
+ --gradient_accumulation_steps=8 \
+ --learning_rate=0.001 \
+ --weight_decay=0.01 \
+ --max_duration_in_seconds=20.0 \
+ --min_duration_in_seconds=2.0 \
+ --model_name_or_path=./
+ --logging_steps=1 \
+ --saving_steps=10000 \
+ --per_device_train_batch_size=2 \
+ --per_device_eval_batch_size=4 \
+ --adam_beta1=0.9 \
+ --adam_beta2=0.98 \
+ --adam_epsilon=1e-06 \
+ --gradient_checkpointing \
+ --mask_time_prob=0.65 \
+ --mask_time_length=10
+```
+
+The experiment was run on 8 GPU V100 (16 GB RAM each) for 7 days.
+In case you have more than 8 GPUs available for a higher effective `batch_size`,
+it is recommended to increase the `learning_rate` to `0.005` for faster convergence.
+
+The results of this run can be seen [here](https://wandb.ai/patrickvonplaten/pretraining-wav2vec2/reports/Wav2Vec2-Large--VmlldzoxMTAwODM4?accessToken=wm3qzcnldrwsa31tkvf2pdmilw3f63d4twtffs86ou016xjbyilh55uoi3mo1qzc) and the checkpoint pretrained for 120,000 steps can be accessed [here](https://huggingface.co/patrickvonplaten/wav2vec2-large-repro-960h-libri-120k-steps)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-pretraining/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-pretraining/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..c270b3a565fac4aa34d441e6471581926f919f04
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-pretraining/requirements.txt
@@ -0,0 +1,5 @@
+datasets >= 1.12.0
+torch >= 1.5
+torchaudio
+accelerate >= 0.12.0
+librosa
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-pretraining/run_wav2vec2_pretraining_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-pretraining/run_wav2vec2_pretraining_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..62b15c0f313831e7b245bae3f9a522471600d7b1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-pretraining/run_wav2vec2_pretraining_no_trainer.py
@@ -0,0 +1,802 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+
+"""Pre-Training a 🤗 Wav2Vec2 model on unlabeled audio data"""
+
+import argparse
+import math
+import os
+from dataclasses import dataclass
+from pathlib import Path
+from typing import Dict, List, Optional, Union
+
+import datasets
+import torch
+from accelerate import Accelerator
+from accelerate.logging import get_logger
+from datasets import DatasetDict, concatenate_datasets, load_dataset
+from huggingface_hub import HfApi
+from torch.utils.data.dataloader import DataLoader
+from tqdm.auto import tqdm
+
+import transformers
+from transformers import (
+ AdamW,
+ SchedulerType,
+ Wav2Vec2Config,
+ Wav2Vec2FeatureExtractor,
+ Wav2Vec2ForPreTraining,
+ get_scheduler,
+ is_wandb_available,
+ set_seed,
+)
+from transformers.models.wav2vec2.modeling_wav2vec2 import _compute_mask_indices, _sample_negative_indices
+from transformers.utils import send_example_telemetry
+
+
+logger = get_logger(__name__)
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Finetune a transformers model on a text classification task")
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ default=None,
+ help="The name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--dataset_config_names",
+ nargs="+",
+ type=str,
+ required=True,
+ help="The configuration names of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--dataset_split_names",
+ nargs="+",
+ type=str,
+ required=True,
+ help="The names of the training data set splits to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--trust_remote_code",
+ action="store_true",
+ help=(
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--preprocessing_num_workers",
+ type=int,
+ default=None,
+ help="The number of processes to use for the preprocessing.",
+ )
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+ parser.add_argument(
+ "--preprocessing_only",
+ action="store_true",
+ help="Only run the preprocessing script to be cached for future use",
+ )
+ parser.add_argument(
+ "--cache_dir",
+ type=str,
+ default=None,
+ help="Where do you want to store the pretrained models downloaded from huggingface.co",
+ )
+ parser.add_argument(
+ "--validation_split_percentage",
+ type=int,
+ default=1,
+ help="Percentage of training data that should be used for validation if no validation is present in dataset.",
+ )
+ parser.add_argument(
+ "--logging_steps",
+ type=int,
+ default=500,
+ help="Number of steps between each logging",
+ )
+ parser.add_argument(
+ "--saving_steps",
+ type=int,
+ default=500,
+ help="Number of steps between each logging",
+ )
+ parser.add_argument(
+ "--audio_column_name",
+ type=str,
+ default="audio",
+ help="Column in the dataset that contains speech file path. Defaults to 'audio'",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=True,
+ )
+ parser.add_argument(
+ "--config_name",
+ type=str,
+ default=None,
+ help="Pretrained config name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--train_cache_file_name",
+ type=str,
+ default=None,
+ help="Path to the train cached file name",
+ )
+ parser.add_argument(
+ "--validation_cache_file_name",
+ type=str,
+ default=None,
+ help="Path to the validation cached file name",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--gradient_checkpointing",
+ action="store_true",
+ help="If True, use gradient checkpointing to save memory at the expense of slower backward pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=0, help="A seed for reproducible training.")
+ parser.add_argument(
+ "--max_gumbel_temperature",
+ type=float,
+ default=2.0,
+ help="Maximum temperature for gumbel softmax.",
+ )
+ parser.add_argument(
+ "--min_gumbel_temperature",
+ type=float,
+ default=0.5,
+ help="Minimum temperature for gumbel softmax.",
+ )
+ parser.add_argument(
+ "--gumbel_temperature_decay", type=float, default=0.999995, help="Decay of gumbel temperature during training."
+ )
+ parser.add_argument(
+ "--max_duration_in_seconds",
+ type=float,
+ default=5.0,
+ help="Filter out audio files that are longer than `max_duration_in_seconds` seconds",
+ )
+ parser.add_argument(
+ "--min_duration_in_seconds",
+ type=float,
+ default=3.0,
+ help="Filter out audio files that are shorter than `min_duration_in_seconds` seconds",
+ )
+ parser.add_argument(
+ "--pad_to_multiple_of",
+ type=int,
+ default=None,
+ help=(
+ "If set will pad the sequence to a multiple of the provided value. This is especially useful to enable the"
+ " use of Tensor Cores on NVIDIA hardware with compute capability >= 7.5 (Volta)."
+ ),
+ )
+ parser.add_argument(
+ "--adam_beta1",
+ type=float,
+ default=0.9,
+ help="Beta1 for AdamW optimizer",
+ )
+ parser.add_argument(
+ "--adam_beta2",
+ type=float,
+ default=0.999,
+ help="Beta2 for AdamW optimizer",
+ )
+ parser.add_argument(
+ "--adam_epsilon",
+ type=float,
+ default=1e-8,
+ help="Epsilon for AdamW optimizer",
+ )
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--mask_time_prob",
+ type=float,
+ default=None,
+ help=(
+ "Percentage (between 0 and 1) of all feature vectors along the time axis which will be masked in the"
+ " contrastive task. If omitted, will pull value from model config."
+ ),
+ )
+ parser.add_argument(
+ "--mask_time_length",
+ type=int,
+ default=None,
+ help=(
+ "Length of each vector mask span to mask along the time axis in the contrastive task."
+ " If omitted, will pull value from model config."
+ ),
+ )
+ args = parser.parse_args()
+
+ if args.push_to_hub:
+ assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
+
+ if args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+
+ return args
+
+
+@dataclass
+class DataCollatorForWav2Vec2Pretraining:
+ """
+ Data collator that will dynamically pad the inputs received and prepare masked indices
+ for self-supervised pretraining.
+
+ Args:
+ model (:class:`~transformers.Wav2Vec2ForPreTraining`):
+ The Wav2Vec2 model used for pretraining. The data collator needs to have access
+ to config and ``_get_feat_extract_output_lengths`` function for correct padding.
+ feature_extractor (:class:`~transformers.Wav2Vec2FeatureExtractor`):
+ The processor used for proccessing the data.
+ padding (:obj:`bool`, :obj:`str` or :class:`~transformers.tokenization_utils_base.PaddingStrategy`, `optional`, defaults to :obj:`True`):
+ Select a strategy to pad the returned sequences (according to the model's padding side and padding index)
+ among:
+ * :obj:`True` or :obj:`'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
+ sequence if provided).
+ * :obj:`'max_length'`: Pad to a maximum length specified with the argument :obj:`max_length` or to the
+ maximum acceptable input length for the model if that argument is not provided.
+ * :obj:`False` or :obj:`'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of
+ different lengths).
+ max_length (:obj:`int`, `optional`):
+ Maximum length of the ``input_values`` of the returned list and optionally padding length (see above).
+ pad_to_multiple_of (:obj:`int`, `optional`):
+ If set will pad the sequence to a multiple of the provided value.
+ This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability >=
+ 7.5 (Volta).
+ mask_time_prob (:obj:`float`, `optional`, defaults to :obj:`0.65`):
+ Percentage (between 0 and 1) of all feature vectors along the time axis which will be masked for the contrastive task.
+ Note that overlap between masked sequences may decrease the actual percentage of masked vectors.
+ The default value is taken from the original wav2vec 2.0 article (https://arxiv.org/abs/2006.11477),
+ and results in about 49 percent of each sequence being masked on average.
+ mask_time_length (:obj:`int`, `optional`, defaults to :obj:`10`):
+ Length of each vector mask span to mask along the time axis in the contrastive task. The default value
+ originates from the original wav2vec 2.0 article and corresponds to the ``M`` variable mentioned there.
+ """
+
+ model: Wav2Vec2ForPreTraining
+ feature_extractor: Wav2Vec2FeatureExtractor
+ padding: Union[bool, str] = "longest"
+ pad_to_multiple_of: Optional[int] = None
+ mask_time_prob: Optional[float] = 0.65
+ mask_time_length: Optional[int] = 10
+
+ def __call__(self, features: List[Dict[str, Union[List[int], torch.Tensor]]]) -> Dict[str, torch.Tensor]:
+ # reformat list to dict and set to pytorch format
+ batch = self.feature_extractor.pad(
+ features,
+ padding=self.padding,
+ pad_to_multiple_of=self.pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ device = batch["input_values"].device
+ batch_size = batch["input_values"].shape[0]
+
+ mask_indices_seq_length = self.model._get_feat_extract_output_lengths(batch["input_values"].shape[-1])
+ # make sure masked sequence length is a Python scalar
+ mask_indices_seq_length = int(mask_indices_seq_length)
+
+ # make sure that no loss is computed on padded inputs
+ if batch.get("attention_mask") is not None:
+ # compute real output lengths according to convolution formula
+ batch["sub_attention_mask"] = self.model._get_feature_vector_attention_mask(
+ mask_indices_seq_length, batch["attention_mask"]
+ )
+
+ features_shape = (batch_size, mask_indices_seq_length)
+
+ # sample randomly masked indices
+ mask_time_indices = _compute_mask_indices(
+ features_shape,
+ self.mask_time_prob,
+ self.mask_time_length,
+ attention_mask=batch.get("sub_attention_mask"),
+ )
+
+ # sample negative indices
+ sampled_negative_indices = _sample_negative_indices(
+ features_shape,
+ self.model.config.num_negatives,
+ mask_time_indices=mask_time_indices,
+ )
+ batch["mask_time_indices"] = torch.tensor(mask_time_indices, dtype=torch.long, device=device)
+ batch["sampled_negative_indices"] = torch.tensor(sampled_negative_indices, dtype=torch.long, device=device)
+
+ return batch
+
+
+def multiply_grads(params, c):
+ """Multiplies grads by a constant *c*."""
+ for p in params:
+ if p.grad is not None:
+ if torch.is_tensor(c):
+ c = c.to(p.grad.device)
+ p.grad.data.mul_(c)
+
+
+def get_grad_norm(params, scale=1):
+ """Compute grad norm given a gradient scale."""
+ total_norm = 0.0
+ for p in params:
+ if p.grad is not None:
+ param_norm = (p.grad.detach().data / scale).norm(2)
+ total_norm += param_norm.item() ** 2
+ total_norm = total_norm**0.5
+ return total_norm
+
+
+def main():
+ # See all possible arguments in src/transformers/args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+ args = parse_args()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_wav2vec2_pretraining_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ accelerator = Accelerator()
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+
+ # set up weights and biases if available
+ if is_wandb_available():
+ import wandb
+
+ wandb.init(project=args.output_dir.split("/")[-1])
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub and not args.preprocessing_only:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # 1. Download and create train, validation dataset
+ # We load all dataset configuration and datset split pairs passed in
+ # ``args.dataset_config_names`` and ``args.dataset_split_names``
+ datasets_splits = []
+ for dataset_config_name, train_split_name in zip(args.dataset_config_names, args.dataset_split_names):
+ # load dataset
+ dataset_split = load_dataset(
+ args.dataset_name,
+ dataset_config_name,
+ split=train_split_name,
+ cache_dir=args.cache_dir,
+ trust_remote_code=args.trust_remote_code,
+ )
+ datasets_splits.append(dataset_split)
+
+ # Next, we concatenate all configurations and splits into a single training dataset
+ raw_datasets = DatasetDict()
+ if len(datasets_splits) > 1:
+ raw_datasets["train"] = concatenate_datasets(datasets_splits).shuffle(seed=args.seed)
+ else:
+ raw_datasets["train"] = datasets_splits[0]
+
+ # Take ``args.validation_split_percentage`` from the training dataset for the validation_split_percentage
+ num_validation_samples = raw_datasets["train"].num_rows * args.validation_split_percentage // 100
+
+ if num_validation_samples == 0:
+ raise ValueError(
+ "`args.validation_split_percentage` is less than a single sample "
+ f"for {len(raw_datasets['train'])} training samples. Increase "
+ "`args.num_validation_split_percentage`. "
+ )
+
+ raw_datasets["validation"] = raw_datasets["train"].select(range(num_validation_samples))
+ raw_datasets["train"] = raw_datasets["train"].select(range(num_validation_samples, raw_datasets["train"].num_rows))
+
+ # 2. Now we preprocess the datasets including loading the audio, resampling and normalization
+ # Thankfully, `datasets` takes care of automatically loading and resampling the audio,
+ # so that we just need to set the correct target sampling rate and normalize the input
+ # via the `feature_extractor`
+ feature_extractor = Wav2Vec2FeatureExtractor.from_pretrained(args.model_name_or_path)
+
+ # make sure that dataset decodes audio with correct sampling rate
+ raw_datasets = raw_datasets.cast_column(
+ args.audio_column_name, datasets.features.Audio(sampling_rate=feature_extractor.sampling_rate)
+ )
+
+ # only normalized-inputs-training is supported
+ if not feature_extractor.do_normalize:
+ raise ValueError(
+ "Training is only supported for normalized inputs. Make sure ``feature_extractor.do_normalize == True``"
+ )
+
+ # set max & min audio length in number of samples
+ max_length = int(args.max_duration_in_seconds * feature_extractor.sampling_rate)
+ min_length = int(args.min_duration_in_seconds * feature_extractor.sampling_rate)
+
+ def prepare_dataset(batch):
+ sample = batch[args.audio_column_name]
+
+ inputs = feature_extractor(
+ sample["array"], sampling_rate=sample["sampling_rate"], max_length=max_length, truncation=True
+ )
+ batch["input_values"] = inputs.input_values[0]
+ batch["input_length"] = len(inputs.input_values[0])
+
+ return batch
+
+ # load via mapped files via path
+ cache_file_names = None
+ if args.train_cache_file_name is not None:
+ cache_file_names = {"train": args.train_cache_file_name, "validation": args.validation_cache_file_name}
+
+ # load audio files into numpy arrays
+ with accelerator.main_process_first():
+ vectorized_datasets = raw_datasets.map(
+ prepare_dataset,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=raw_datasets["train"].column_names,
+ cache_file_names=cache_file_names,
+ )
+
+ if min_length > 0.0:
+ vectorized_datasets = vectorized_datasets.filter(
+ lambda x: x > min_length,
+ num_proc=args.preprocessing_num_workers,
+ input_columns=["input_length"],
+ )
+
+ vectorized_datasets = vectorized_datasets.remove_columns("input_length")
+
+ # for large datasets it is advised to run the preprocessing on a
+ # single machine first with ``args.preprocessing_only`` since there will mostly likely
+ # be a timeout when running the script in distributed mode.
+ # In a second step ``args.preprocessing_only`` can then be set to `False` to load the
+ # cached dataset
+ if args.preprocessing_only:
+ return
+
+ # 3. Load model
+ config = Wav2Vec2Config.from_pretrained(args.model_name_or_path)
+
+ # pretraining is only supported for "newer" stable layer norm architecture
+ # apply_spec_augment has to be True, mask_feature_prob has to be 0.0
+ if not config.do_stable_layer_norm or config.feat_extract_norm != "layer":
+ raise ValueError(
+ "PreTraining is only supported for ``config.do_stable_layer_norm=True`` and"
+ " ``config.feat_extract_norm='layer'"
+ )
+
+ # initialize random model
+ model = Wav2Vec2ForPreTraining(config)
+
+ # Activate gradient checkpointing if needed
+ if args.gradient_checkpointing:
+ model.gradient_checkpointing_enable()
+
+ # 4. Define data collator, optimizer and scheduler
+
+ mask_time_prob = config.mask_time_prob if args.mask_time_prob is None else args.mask_time_prob
+ mask_time_length = config.mask_time_length if args.mask_time_length is None else args.mask_time_length
+
+ data_collator = DataCollatorForWav2Vec2Pretraining(
+ model=model,
+ feature_extractor=feature_extractor,
+ pad_to_multiple_of=args.pad_to_multiple_of,
+ mask_time_prob=mask_time_prob,
+ mask_time_length=mask_time_length,
+ )
+ train_dataloader = DataLoader(
+ vectorized_datasets["train"],
+ shuffle=True,
+ collate_fn=data_collator,
+ batch_size=args.per_device_train_batch_size,
+ )
+ eval_dataloader = DataLoader(
+ vectorized_datasets["validation"], collate_fn=data_collator, batch_size=args.per_device_eval_batch_size
+ )
+
+ # Optimizer
+ optimizer = AdamW(
+ list(model.parameters()),
+ lr=args.learning_rate,
+ betas=[args.adam_beta1, args.adam_beta2],
+ eps=args.adam_epsilon,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader
+ )
+
+ # Scheduler and math around the number of training steps.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps,
+ num_training_steps=args.max_train_steps,
+ )
+
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # 5. Train
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(vectorized_datasets['train'])}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ completed_steps = 0
+ starting_epoch = 0
+
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ for step, batch in enumerate(train_dataloader):
+ # compute num of losses
+ num_losses = batch["mask_time_indices"].sum()
+ sub_attention_mask = batch.pop("sub_attention_mask", None)
+ sub_attention_mask = (
+ sub_attention_mask if sub_attention_mask is not None else torch.ones_like(batch["mask_time_indices"])
+ )
+ percent_masked = num_losses / sub_attention_mask.sum()
+
+ # forward
+ outputs = model(**batch)
+
+ # divide loss by gradient accumulation steps since gradients
+ # are accumulated for multiple backward passes in PyTorch
+ loss = outputs.loss / args.gradient_accumulation_steps
+ accelerator.backward(loss)
+
+ # make sure that `num_losses` is summed for distributed training
+ # and average gradients over losses of all devices
+ if accelerator.state.num_processes > 1:
+ num_losses = accelerator.gather_for_metrics(num_losses).sum()
+ gradient_multiplier = accelerator.state.num_processes / num_losses
+ multiply_grads(model.module.parameters(), gradient_multiplier)
+ else:
+ multiply_grads(model.parameters(), 1 / num_losses)
+
+ # update step
+ if (step + 1) % args.gradient_accumulation_steps == 0 or step == len(train_dataloader) - 1:
+ # compute grad norm for monitoring
+ scale = (
+ accelerator.scaler._scale.item()
+ if hasattr(accelerator, "scaler") and accelerator.scaler is not None
+ else 1
+ )
+ if accelerator.state.num_processes > 1:
+ grad_norm = get_grad_norm(model.module.parameters(), scale)
+ else:
+ grad_norm = get_grad_norm(model.parameters(), scale)
+
+ # update parameters
+ optimizer.step()
+ optimizer.zero_grad()
+
+ if not accelerator.optimizer_step_was_skipped:
+ lr_scheduler.step()
+ elif accelerator.is_local_main_process:
+ progress_bar.write(
+ f"Gradients have overflown - skipping update step... Updating gradient scale to {scale}..."
+ )
+
+ # update gumbel temperature
+ gumbel_temperature = max(
+ args.max_gumbel_temperature * args.gumbel_temperature_decay**completed_steps,
+ args.min_gumbel_temperature,
+ )
+ if hasattr(model, "module"):
+ model.module.set_gumbel_temperature(gumbel_temperature)
+ else:
+ model.set_gumbel_temperature(gumbel_temperature)
+
+ progress_bar.update(1)
+ completed_steps += 1
+
+ # 6. Log all results
+ if (step + 1) % (args.gradient_accumulation_steps * args.logging_steps) == 0:
+ loss.detach()
+ outputs.contrastive_loss.detach()
+ outputs.diversity_loss.detach()
+
+ if accelerator.state.num_processes > 1:
+ loss = accelerator.gather_for_metrics(loss).sum()
+ outputs.contrastive_loss = accelerator.gather_for_metrics(outputs.contrastive_loss).sum()
+ outputs.diversity_loss = accelerator.gather_for_metrics(outputs.diversity_loss).sum()
+ percent_masked = accelerator.gather_for_metrics(percent_masked).sum()
+
+ train_logs = {
+ "loss": (loss * args.gradient_accumulation_steps) / num_losses,
+ "constrast_loss": outputs.contrastive_loss / num_losses,
+ "div_loss": outputs.diversity_loss / num_losses,
+ "%_mask_idx": percent_masked / accelerator.num_processes,
+ "ppl": outputs.codevector_perplexity,
+ "lr": torch.tensor(optimizer.param_groups[0]["lr"]),
+ "temp": torch.tensor(gumbel_temperature),
+ "grad_norm": torch.tensor(grad_norm),
+ }
+ log_str = ""
+ for k, v in train_logs.items():
+ log_str += "| {}: {:.3e}".format(k, v.item())
+
+ if accelerator.is_local_main_process:
+ progress_bar.write(log_str)
+ if is_wandb_available():
+ wandb.log(train_logs)
+
+ # save model every `args.saving_steps` steps
+ if (step + 1) % (args.gradient_accumulation_steps * args.saving_steps) == 0:
+ if (args.push_to_hub and epoch < args.num_train_epochs - 1) or args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+
+ if (args.push_to_hub and epoch < args.num_train_epochs - 1) and accelerator.is_main_process:
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ # if completed steps > `args.max_train_steps` stop
+ if completed_steps >= args.max_train_steps:
+ break
+
+ # 7. Validate!
+ model.eval()
+
+ # init logs
+ val_logs = {
+ "val_loss": 0,
+ "val_contrastive_loss": 0,
+ "val_diversity_loss": 0,
+ "val_num_losses": 0,
+ }
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ batch.pop("sub_attention_mask", None)
+ outputs = model(**batch)
+
+ val_logs["val_loss"] += outputs.loss
+ val_logs["val_contrastive_loss"] += outputs.contrastive_loss
+ val_logs["val_diversity_loss"] += outputs.diversity_loss
+ val_logs["val_num_losses"] += batch["mask_time_indices"].sum()
+
+ # sum over devices in multi-processing
+ if accelerator.num_processes > 1:
+ val_logs = {k: accelerator.gather_for_metrics(v).sum() for k, v in val_logs.items()}
+
+ val_logs = {k: v / val_logs["val_num_losses"] for k, v in val_logs.items()}
+
+ log_str = ""
+ for k, v in val_logs.items():
+ log_str += "| {}: {:.3e}".format(k, v.item())
+
+ if accelerator.is_local_main_process:
+ progress_bar.write(log_str)
+ if is_wandb_available():
+ wandb.log(val_logs)
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ api.upload_folder(
+ commit_message="End of training",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-recognition/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-recognition/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..4990219f42a143a799201f6d044b624942dd08e8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-recognition/README.md
@@ -0,0 +1,617 @@
+
+
+# Automatic Speech Recognition Examples
+
+## Table of Contents
+
+- [Automatic Speech Recognition with CTC](#connectionist-temporal-classification)
+ - [Single GPU example](#single-gpu-ctc)
+ - [Multi GPU example](#multi-gpu-ctc)
+ - [Examples](#examples-ctc)
+ - [TIMIT](#timit-ctc)
+ - [Librispeech](#librispeech-ctc)
+ - [Common Voice](#common-voice-ctc)
+ - [Multilingual Librispeech](#multilingual-librispeech-ctc)
+- [Automatic Speech Recognition with CTC and Adapter Layers](#connectionist-temporal-classification-with-adapters)
+ - [Massive Multilingual Speech (MMS)](#mms-model)
+ - [Examples](#examples-ctc-adapter)
+ - [Common Voice](#common-voice-ctc-adapter)
+- [Automatic Speech Recognition with Sequence-to-Sequence](#sequence-to-sequence)
+ - [Whisper Model](#whisper-model)
+ - [Speech-Encoder-Decoder Model](#warm-started-speech-encoder-decoder-model)
+ - [Examples](#examples-seq2seq)
+ - [Librispeech](#librispeech-seq2seq)
+
+## Connectionist Temporal Classification
+
+The script [`run_speech_recognition_ctc.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/speech-recognition/run_speech_recognition_ctc.py) can be used to fine-tune any pretrained [Connectionist Temporal Classification Model](https://huggingface.co/docs/transformers/main/en/model_doc/auto#transformers.AutoModelForCTC) for automatic speech
+recognition on one of the [official speech recognition datasets](https://huggingface.co/datasets?task_ids=task_ids:automatic-speech-recognition) or a custom dataset.
+
+Speech recognition models that have been pretrained in unsupervised fashion on audio data alone, *e.g.* [Wav2Vec2](https://huggingface.co/transformers/main/model_doc/wav2vec2.html), [HuBERT](https://huggingface.co/transformers/main/model_doc/hubert.html), [XLSR-Wav2Vec2](https://huggingface.co/transformers/main/model_doc/xlsr_wav2vec2.html), have shown to require only
+very little annotated data to yield good performance on automatic speech recognition datasets.
+
+In the script [`run_speech_recognition_ctc`], we first create a vocabulary from all unique characters of both the training data and evaluation data. Then, we preprocesses the speech recognition dataset, which includes correct resampling, normalization and padding. Finally, the pretrained speech recognition model is fine-tuned on the annotated speech recognition datasets using CTC loss.
+
+---
+**NOTE**
+
+If you encounter problems with data preprocessing by setting `--preprocessing_num_workers` > 1,
+you might want to set the environment variable `OMP_NUM_THREADS` to 1 as follows:
+
+```bash
+OMP_NUM_THREADS=1 python run_speech_recognition_ctc ...
+```
+
+If the environment variable is not set, the training script might freeze, *i.e.* see: https://github.com/pytorch/audio/issues/1021#issuecomment-726915239
+
+---
+
+### Single GPU CTC
+
+The following command shows how to fine-tune [XLSR-Wav2Vec2](https://huggingface.co/transformers/main/model_doc/xlsr_wav2vec2.html) on [Common Voice](https://huggingface.co/datasets/common_voice) using a single GPU in half-precision.
+
+```bash
+python run_speech_recognition_ctc.py \
+ --dataset_name="common_voice" \
+ --model_name_or_path="facebook/wav2vec2-large-xlsr-53" \
+ --dataset_config_name="tr" \
+ --output_dir="./wav2vec2-common_voice-tr-demo" \
+ --overwrite_output_dir \
+ --num_train_epochs="15" \
+ --per_device_train_batch_size="16" \
+ --gradient_accumulation_steps="2" \
+ --learning_rate="3e-4" \
+ --warmup_steps="500" \
+ --eval_strategy="steps" \
+ --text_column_name="sentence" \
+ --length_column_name="input_length" \
+ --save_steps="400" \
+ --eval_steps="100" \
+ --layerdrop="0.0" \
+ --save_total_limit="3" \
+ --freeze_feature_encoder \
+ --gradient_checkpointing \
+ --chars_to_ignore , ? . ! - \; \: \" “ % ‘ ” � \
+ --fp16 \
+ --group_by_length \
+ --push_to_hub \
+ --do_train --do_eval
+```
+
+On a single V100 GPU, this script should run in *ca.* 1 hour 20 minutes and yield a CTC loss of **0.39** and word error rate
+of **0.35**.
+
+### Multi GPU CTC
+
+The following command shows how to fine-tune [XLSR-Wav2Vec2](https://huggingface.co/transformers/main/model_doc/xlsr_wav2vec2.html) on [Common Voice](https://huggingface.co/datasets/common_voice) using 8 GPUs in half-precision.
+
+```bash
+torchrun \
+ --nproc_per_node 8 run_speech_recognition_ctc.py \
+ --dataset_name="common_voice" \
+ --model_name_or_path="facebook/wav2vec2-large-xlsr-53" \
+ --dataset_config_name="tr" \
+ --output_dir="./wav2vec2-common_voice-tr-demo-dist" \
+ --overwrite_output_dir \
+ --num_train_epochs="15" \
+ --per_device_train_batch_size="4" \
+ --learning_rate="3e-4" \
+ --warmup_steps="500" \
+ --eval_strategy="steps" \
+ --text_column_name="sentence" \
+ --length_column_name="input_length" \
+ --save_steps="400" \
+ --eval_steps="100" \
+ --logging_steps="1" \
+ --layerdrop="0.0" \
+ --save_total_limit="3" \
+ --freeze_feature_encoder \
+ --gradient_checkpointing \
+ --chars_to_ignore , ? . ! - \; \: \" “ % ‘ ” � \
+ --fp16 \
+ --group_by_length \
+ --push_to_hub \
+ --do_train --do_eval
+```
+
+On 8 V100 GPUs, this script should run in *ca.* 18 minutes and yield a CTC loss of **0.39** and word error rate
+of **0.36**.
+
+
+### Multi GPU CTC with Dataset Streaming
+
+The following command shows how to use [Dataset Streaming mode](https://huggingface.co/docs/datasets/dataset_streaming)
+to fine-tune [XLS-R](https://huggingface.co/transformers/main/model_doc/xls_r.html)
+on [Common Voice](https://huggingface.co/datasets/common_voice) using 4 GPUs in half-precision.
+
+Streaming mode imposes several constraints on training:
+1. We need to construct a tokenizer beforehand and define it via `--tokenizer_name_or_path`.
+2. `--num_train_epochs` has to be replaced by `--max_steps`. Similarly, all other epoch-based arguments have to be
+replaced by step-based ones.
+3. Full dataset shuffling on each epoch is not possible, since we don't have the whole dataset available at once.
+However, the `--shuffle_buffer_size` argument controls how many examples we can pre-download before shuffling them.
+
+
+```bash
+**torchrun \
+ --nproc_per_node 4 run_speech_recognition_ctc_streaming.py \
+ --dataset_name="common_voice" \
+ --model_name_or_path="facebook/wav2vec2-xls-r-300m" \
+ --tokenizer_name_or_path="anton-l/wav2vec2-tokenizer-turkish" \
+ --dataset_config_name="tr" \
+ --train_split_name="train+validation" \
+ --eval_split_name="test" \
+ --output_dir="wav2vec2-xls-r-common_voice-tr-ft" \
+ --overwrite_output_dir \
+ --max_steps="5000" \
+ --per_device_train_batch_size="8" \
+ --gradient_accumulation_steps="2" \
+ --learning_rate="5e-4" \
+ --warmup_steps="500" \
+ --eval_strategy="steps" \
+ --text_column_name="sentence" \
+ --save_steps="500" \
+ --eval_steps="500" \
+ --logging_steps="1" \
+ --layerdrop="0.0" \
+ --eval_metrics wer cer \
+ --save_total_limit="1" \
+ --mask_time_prob="0.3" \
+ --mask_time_length="10" \
+ --mask_feature_prob="0.1" \
+ --mask_feature_length="64" \
+ --freeze_feature_encoder \
+ --chars_to_ignore , ? . ! - \; \: \" “ % ‘ ” � \
+ --max_duration_in_seconds="20" \
+ --shuffle_buffer_size="500" \
+ --fp16 \
+ --push_to_hub \
+ --do_train --do_eval \
+ --gradient_checkpointing**
+```
+
+On 4 V100 GPUs, this script should run in *ca.* 3h 31min and yield a CTC loss of **0.35** and word error rate
+of **0.29**.
+
+### Examples CTC
+
+The following tables present a couple of example runs on the most popular speech-recognition datasets.
+The presented performances are by no means optimal as no hyper-parameter tuning was done. Nevertheless,
+they can serve as a baseline to improve upon.
+
+
+#### TIMIT CTC
+
+- [TIMIT](https://huggingface.co/datasets/timit_asr)
+
+| Dataset | Dataset Config | Pretrained Model | Word error rate on eval | Phoneme error rate on eval | GPU setup | Training time | Fine-tuned Model & Logs | Command to reproduce |
+|-------|------------------------------|-------------|---------------|---------------|----------------------|-------------| -------------| ------- |
+| [TIMIT](https://huggingface.co/datasets/timit_asr)| - | [wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base) | 0.21 | - | 1 GPU TITAN RTX | 32min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-base-timit-fine-tuned) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-base-timit-fine-tuned/blob/main/run.sh) |
+| [TIMIT](https://huggingface.co/datasets/timit_asr)| - | [wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base) | 0.21 | - | 1 GPU TITAN RTX | 32min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-base-timit-fine-tuned) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-base-timit-fine-tuned/blob/main/run.sh) |
+| [TIMIT](https://huggingface.co/datasets/timit_asr)| - | [unispeech-large-1500h-cv](https://huggingface.co/microsoft/unispeech-large-1500h-cv) | 0.22 | - | 1 GPU TITAN RTX | 35min | [here](https://huggingface.co/patrickvonplaten/unispeech-large-1500h-cv-timit) | [run.sh](https://huggingface.co/patrickvonplaten/unispeech-large-1500h-cv-timit/blob/main/run.sh) |
+| [TIMIT](https://huggingface.co/datasets/timit_asr)| - | [asapp/sew-mid-100k](https://huggingface.co/asapp/sew-mid-100k) | 0.30 | - | 1 GPU TITAN RTX | 28min | [here](https://huggingface.co/patrickvonplaten/sew-small-100k-timit) | [run.sh](https://huggingface.co/patrickvonplaten/sew-small-100k-timit/blob/main/run.sh) |
+| [TIMIT](https://huggingface.co/datasets/timit_asr)| - | [ntu-spml/distilhubert](https://huggingface.co/ntu-spml/distilhubert) | 0.68 | - | 1 GPU TITAN RTX | 26min | [here](https://huggingface.co/patrickvonplaten/distilhubert-timit) | [run.sh](https://huggingface.co/patrickvonplaten/distilhubert-timit/blob/main/run.sh) |
+
+
+#### Librispeech CTC
+
+- [Librispeech](https://huggingface.co/datasets/librispeech_asr)
+
+| Dataset | Dataset Config | Pretrained Model | Word error rate on eval | Phoneme error rate on eval | GPU setup | Training time | Fine-tuned Model & Logs | Command to reproduce |
+|-------|------------------------------|-------------|---------------|---------------|----------------------|-------------| -------------| ------- |
+| [Librispeech](https://huggingface.co/datasets/librispeech_asr)| `"clean"` - `"train.100"` | [microsoft/wavlm-large](https://huggingface.co/microsoft/wavlm-large) | 0.049 | - | 8 GPU V100 | 1h30min | [here](https://huggingface.co/patrickvonplaten/wavlm-libri-clean-100h-large) | [run.sh](https://huggingface.co/patrickvonplaten/wavlm-libri-clean-100h-large/blob/main/run.sh) |
+| [Librispeech](https://huggingface.co/datasets/librispeech_asr)| `"clean"` - `"train.100"` | [microsoft/wavlm-base-plus](https://huggingface.co/microsoft/wavlm-base-plus) | 0.068 | - | 8 GPU V100 | 1h30min | [here](https://huggingface.co/patrickvonplaten/wavlm-libri-clean-100h-base-plus) | [run.sh](https://huggingface.co/patrickvonplaten/wavlm-libri-clean-100h-base-plus/blob/main/run.sh) |
+| [Librispeech](https://huggingface.co/datasets/librispeech_asr)| `"clean"` - `"train.100"` | [facebook/wav2vec2-large-lv60](https://huggingface.co/facebook/wav2vec2-large-lv60) | 0.042 | - | 8 GPU V100 | 1h30min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-librispeech-clean-100h-demo-dist) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-librispeech-clean-100h-demo-dist/blob/main/run.sh) |
+| [Librispeech](https://huggingface.co/datasets/librispeech_asr)| `"clean"` - `"train.100"` | [facebook/wav2vec2-large-lv60](https://huggingface.co/facebook/wav2vec2-large-lv60) | 0.042 | - | 8 GPU V100 | 1h30min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-librispeech-clean-100h-demo-dist) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-librispeech-clean-100h-demo-dist/blob/main/run.sh) |
+| [Librispeech](https://huggingface.co/datasets/librispeech_asr)| `"clean"` - `"train.100"` | [facebook/hubert-large-ll60k](https://huggingface.co/facebook/hubert-large-ll60k) | 0.088 | - | 8 GPU V100 | 1h30min | [here](https://huggingface.co/patrickvonplaten/hubert-librispeech-clean-100h-demo-dist) | [run.sh](https://huggingface.co/patrickvonplaten/hubert-librispeech-clean-100h-demo-dist/blob/main/run.sh) |
+| [Librispeech](https://huggingface.co/datasets/librispeech_asr)| `"clean"` - `"train.100"` | [asapp/sew-mid-100k](https://huggingface.co/asapp/sew-mid-100k) | 0.167 | | 8 GPU V100 | 54min | [here](https://huggingface.co/patrickvonplaten/sew-mid-100k-librispeech-clean-100h-ft) | [run.sh](https://huggingface.co/patrickvonplaten/sew-mid-100k-librispeech-clean-100h-ft/blob/main/run.sh) |
+
+
+#### Common Voice CTC
+
+- [Common Voice](https://huggingface.co/datasets/common_voice)
+
+| Dataset | Dataset Config | Pretrained Model | Word error rate on eval | Phoneme error rate on eval | GPU setup | Training time | Fine-tuned Model & Logs | Command to reproduce |
+|-------|------------------------------|-------------|---------------|---------------|----------------------|-------------| -------------| ------- |
+| [Common Voice](https://huggingface.co/datasets/mozilla-foundation/common_voice_3_0)| `"tr"` | [facebook/wav2vec2-large-xls-r-300m](https://huggingface.co/facebook/wav2vec2-xls-r-300m) | - | 0.099 | 8 GPU V100 | 23min | [here](https://huggingface.co/patrickvonplaten/xls-r-300m-tr-phoneme) | [run.sh](https://huggingface.co/patrickvonplaten/xls-r-300m-tr-phoneme/blob/main/run.sh) |
+| [Common Voice](https://huggingface.co/datasets/mozilla-foundation/common_voice_3_0)| `"it"` | [facebook/wav2vec2-large-xls-r-300m](https://huggingface.co/facebook/wav2vec2-xls-r-300m) | - | 0.077 | 8 GPU V100 | 23min | [here](https://huggingface.co/patrickvonplaten/xls-r-300m-it-phoneme) | [run.sh](https://huggingface.co/patrickvonplaten/xls-r-300m-it-phoneme/blob/main/run.sh) |
+| [Common Voice](https://huggingface.co/datasets/mozilla-foundation/common_voice_3_0)| `"sv-SE"` | [facebook/wav2vec2-large-xls-r-300m](https://huggingface.co/facebook/wav2vec2-xls-r-300m) | - | 0.099 | 8 GPU V100 | 23min | [here](https://huggingface.co/patrickvonplaten/xls-r-300m-sv-phoneme) | [run.sh](https://huggingface.co/patrickvonplaten/xls-r-300m-sv-phoneme/blob/main/run.sh) |
+| [Common Voice](https://huggingface.co/datasets/common_voice)| `"tr"` | [facebook/wav2vec2-large-xlsr-53](https://huggingface.co/facebook/wav2vec2-large-xlsr-53) | 0.36 | - | 8 GPU V100 | 18min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-common_voice-tr-demo-dist) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-common_voice-tr-demo-dist/blob/main/run_dist.sh) |
+| [Common Voice](https://huggingface.co/datasets/common_voice)| `"tr"` | [facebook/wav2vec2-large-xlsr-53](https://huggingface.co/facebook/wav2vec2-large-xlsr-53) | 0.31 | - | 8 GPU V100 | 1h05 | [here](https://huggingface.co/patrickvonplaten/wav2vec2-large-xlsr-53-common_voice-tr-ft) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-large-xlsr-53-common_voice-tr-ft/blob/main/run.sh) |
+| [Common Voice](https://huggingface.co/datasets/common_voice)| `"tr"` | [facebook/wav2vec2-large-xlsr-53](https://huggingface.co/facebook/wav2vec2-large-xlsr-53) | 0.35 | - | 1 GPU V100 | 1h20min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-common_voice-tr-demo) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-common_voice-tr-demo/blob/main/run.sh) |
+| [Common Voice](https://huggingface.co/datasets/common_voice)| `"tr"` | [facebook/wav2vec2-xls-r-300m](https://huggingface.co/facebook/wav2vec2-xls-r-300m) | 0.31 | - | 8 GPU V100 | 1h05 | [here](https://huggingface.co/patrickvonplaten/wav2vec2-large-xls-r-300m-common_voice-tr-ft) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-large-xls-r-300m-common_voice-tr-ft/blob/main/run.sh) |
+| [Common Voice](https://huggingface.co/datasets/common_voice)| `"tr"` | [facebook/wav2vec2-xls-r-1b](https://huggingface.co/facebook/wav2vec2-xls-r-1b) | 0.21 | - | 2 GPU Titan 24 GB RAM | 15h10 | [here](https://huggingface.co/patrickvonplaten/wav2vec2-xls-r-1b-common_voice-tr-ft) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-large-xls-r-1b-common_voice-tr-ft/blob/main/run.sh) |
+| [Common Voice](https://huggingface.co/datasets/common_voice)| `"tr"` in streaming mode | [facebook/wav2vec2-xls-r-300m](https://huggingface.co/facebook/wav2vec2-xls-r-300m) | 0.29 | - | 4 GPU V100 | 3h31 | [here](https://huggingface.co/anton-l/wav2vec2-xls-r-common_voice-tr-ft-stream) | [run.sh](https://huggingface.co/anton-l/wav2vec2-xls-r-common_voice-tr-ft-stream/blob/main/run.sh) |
+
+
+#### Multilingual Librispeech CTC
+
+- [Multilingual Librispeech](https://huggingface.co/datasets/multilingual_librispeech)
+
+| Dataset | Dataset Config | Pretrained Model | Word error rate on eval | Phoneme error rate on eval | GPU setup | Training time | Fine-tuned Model & Logs | Command to reproduce |
+|-------|------------------------------|-------------|---------------|---------------|----------------------|-------------| -------------| ------- |
+| [Multilingual Librispeech](https://huggingface.co/datasets/multilingual_librispeech)| `"german"` | [facebook/wav2vec2-large-xlsr-53](https://huggingface.co/facebook/wav2vec2-large-xlsr-53) | 0.13 | - | 1 GPU Titan 24 GB RAM | 15h04 | [here](https://huggingface.co/patrickvonplaten/wav2vec2-xlsr-53-300m-mls-german-ft) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-xlsr-53-300m-mls-german-ft/blob/main/run.sh) |
+| [Multilingual Librispeech](https://huggingface.co/datasets/multilingual_librispeech)| `"german"` | [facebook/wav2vec2-xls-r-300m](https://huggingface.co/facebook/wav2vec2-xls-r-300m) | 0.15 | - | 1 GPU Titan 24 GB RAM | 15h04 | [here](https://huggingface.co/patrickvonplaten/wav2vec2-300m-mls-german-ft) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-300m-mls-german-ft/blob/main/run.sh) |
+
+## Connectionist Temporal Classification With Adapters
+
+The script [`run_speech_recognition_ctc_adapter.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/speech-recognition/run_speech_recognition_ctc_adapter.py) can be used to fine-tune adapter layers for [Wav2Vec2-like models like MMS](https://huggingface.co/docs/transformers/main/en/model_doc/mms) for automatic speech recognition.
+
+### MMS Model
+
+The [Massive Multilingual Speech (MMS) model](https://huggingface.co/facebook/mms-1b-all) has been pre-trained and fine-tuned
+on 1000+ languages. The model makes use of adapter attention layers to fine-tune only a small part
+of the model on a specific language. The model already comes with fine-tuned adapter layers for 1000+ languages and
+can be used for inference for 1000+ languages out of the box.
+
+However, for improved performance or more specific use cases one can re-initialize the adapter weights, freeze all
+other weights and fine-tune them on a specific dataset as shown in the [example below](#examples-ctc-adapter).
+
+Note that the adapter weights include low dimensional linear layers for every attention block as well as the final language
+model head layers.
+
+### Examples CTC Adapter
+
+In the following we will look at how one can fine-tune adapter weights for any of the
+[MMS CTC checkpoints](https://huggingface.co/models?pipeline_tag=automatic-speech-recognition&other=mms&sort=downloads) in less than 1 hour.
+
+#### Common Voice CTC Adapter
+
+As in the examples [above](#examples-ctc), we fine-tune on Common Voice's 6 dataset in Turkish as an example.
+Contrary to [`run_speech_recognition_ctc.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/speech-recognition/run_speech_recognition_ctc.py) before there is a `--target_language` which has to be defined to state for which
+language or concept the adapter layers shall be trained. The adapter weights will then
+accordingly be called `adapter.{/wav2vec2-2-bart-base
+cd wav2vec2-2-bart-base
+```
+
+Next, run the following script **inside** the just cloned repo:
+
+```python
+from transformers import SpeechEncoderDecoderModel, AutoFeatureExtractor, AutoTokenizer, Wav2Vec2Processor
+
+# checkpoints to leverage
+encoder_id = "facebook/wav2vec2-base"
+decoder_id = "facebook/bart-base"
+
+# load and save speech-encoder-decoder model
+# set some hyper-parameters for training and evaluation
+model = SpeechEncoderDecoderModel.from_encoder_decoder_pretrained(encoder_id, decoder_id, encoder_add_adapter=True, encoder_feat_proj_dropout=0.0, encoder_layerdrop=0.0, max_length=200, num_beams=5)
+model.config.decoder_start_token_id = model.decoder.config.bos_token_id
+model.config.pad_token_id = model.decoder.config.pad_token_id
+model.config.eos_token_id = model.decoder.config.eos_token_id
+model.save_pretrained("./")
+
+# load and save processor
+feature_extractor = AutoFeatureExtractor.from_pretrained(encoder_id)
+tokenizer = AutoTokenizer.from_pretrained(decoder_id)
+processor = Wav2Vec2Processor(feature_extractor, tokenizer)
+processor.save_pretrained("./")
+```
+
+Finally, we can upload all files:
+```bash
+git lfs install
+git add . && git commit -m "upload model files" && git push
+```
+
+and link the official `run_speech_recognition_seq2seq.py` script to the folder:
+
+```bash
+ln -s $(realpath /examples/pytorch/speech-recognition/run_speech_recognition_seq2seq.py) ./
+```
+
+Note that we have added a randomly initialized _adapter layer_ to `wav2vec2-base` with the argument
+`encoder_add_adapter=True`. This adapter sub-samples the output sequence of
+`wav2vec2-base` along the time dimension. By default, a single
+output vector of `wav2vec2-base` has a receptive field of *ca.* 25ms (*cf.*
+Section *4.2* of the [official Wav2Vec2 paper](https://arxiv.org/pdf/2006.11477.pdf)), which represents a little less a single character. On the other hand, BART
+makes use of a sentence-piece tokenizer as an input processor, so that a single
+hidden vector of `bart-base` represents *ca.* 4 characters. To better align the
+receptive field of the *Wav2Vec2* output vectors with *BART*'s hidden-states in the cross-attention
+mechanism, we further subsample *Wav2Vec2*'s output by a factor of 8 by
+adding a convolution-based adapter.
+
+Having warm-started the speech-encoder-decoder model under `/wav2vec2-2-bart`, we can now fine-tune it on the task of speech recognition.
+
+In the script [`run_speech_recognition_seq2seq`], we load the warm-started model,
+feature extractor, and tokenizer, process a speech recognition dataset,
+and subsequently make use of the [`Seq2SeqTrainer`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.Seq2SeqTrainer) to train our system.
+Note that it is important to align the target transcriptions with the decoder's vocabulary. For example, the [`Librispeech`](https://huggingface.co/datasets/librispeech_asr) dataset only contains capitalized letters in the transcriptions,
+whereas BART was pretrained mostly on normalized text. Thus, it is recommended to add the argument
+`--do_lower_case` to the fine-tuning script when using a warm-started `SpeechEncoderDecoderModel`.
+The model is fine-tuned on the standard cross-entropy language modeling
+loss for sequence-to-sequence (just like *T5* or *BART* in natural language processing).
+
+---
+**NOTE**
+
+If you encounter problems with data preprocessing by setting `--preprocessing_num_workers` > 1,
+you might want to set the environment variable `OMP_NUM_THREADS` to 1 as follows:
+
+```bash
+OMP_NUM_THREADS=1 python run_speech_recognition_ctc ...
+```
+
+If the environment variable is not set, the training script might freeze, *i.e.* see: https://github.com/pytorch/audio/issues/1021#issuecomment-726915239.
+
+---
+
+#### Single GPU Seq2Seq
+
+The following command shows how to fine-tune [XLSR-Wav2Vec2](https://huggingface.co/transformers/main/model_doc/xlsr_wav2vec2.html) on [Common Voice](https://huggingface.co/datasets/common_voice) using a single GPU in half-precision.
+
+```bash
+python run_speech_recognition_seq2seq.py \
+ --dataset_name="librispeech_asr" \
+ --model_name_or_path="./" \
+ --dataset_config_name="clean" \
+ --train_split_name="train.100" \
+ --eval_split_name="validation" \
+ --output_dir="./" \
+ --preprocessing_num_workers="16" \
+ --length_column_name="input_length" \
+ --overwrite_output_dir \
+ --num_train_epochs="5" \
+ --per_device_train_batch_size="8" \
+ --per_device_eval_batch_size="8" \
+ --gradient_accumulation_steps="8" \
+ --learning_rate="3e-4" \
+ --warmup_steps="400" \
+ --eval_strategy="steps" \
+ --text_column_name="text" \
+ --save_steps="400" \
+ --eval_steps="400" \
+ --logging_steps="10" \
+ --save_total_limit="1" \
+ --freeze_feature_encoder \
+ --gradient_checkpointing \
+ --fp16 \
+ --group_by_length \
+ --predict_with_generate \
+ --generation_max_length="40" \
+ --generation_num_beams="1" \
+ --do_train --do_eval \
+ --do_lower_case
+```
+
+On a single V100 GPU, this script should run in *ca.* 5 hours and yield a
+cross-entropy loss of **0.405** and word error rate of **0.0728**.
+
+#### Multi GPU Seq2Seq
+
+The following command shows how to fine-tune [XLSR-Wav2Vec2](https://huggingface.co/transformers/main/model_doc/xlsr_wav2vec2.html) on [Common Voice](https://huggingface.co/datasets/common_voice) using 8 GPUs in half-precision.
+
+```bash
+torchrun \
+ --nproc_per_node 8 run_speech_recognition_seq2seq.py \
+ --dataset_name="librispeech_asr" \
+ --model_name_or_path="./" \
+ --dataset_config_name="clean" \
+ --train_split_name="train.100" \
+ --eval_split_name="validation" \
+ --output_dir="./" \
+ --preprocessing_num_workers="16" \
+ --length_column_name="input_length" \
+ --overwrite_output_dir \
+ --num_train_epochs="5" \
+ --per_device_train_batch_size="8" \
+ --per_device_eval_batch_size="8" \
+ --gradient_accumulation_steps="1" \
+ --learning_rate="3e-4" \
+ --warmup_steps="400" \
+ --eval_strategy="steps" \
+ --text_column_name="text" \
+ --save_steps="400" \
+ --eval_steps="400" \
+ --logging_steps="10" \
+ --save_total_limit="1" \
+ --freeze_feature_encoder \
+ --gradient_checkpointing \
+ --fp16 \
+ --group_by_length \
+ --predict_with_generate \
+ --do_train --do_eval \
+ --do_lower_case
+```
+
+On 8 V100 GPUs, this script should run in *ca.* 45 minutes and yield a cross-entropy loss of **0.405** and word error rate of **0.0728**
+
+### Examples Seq2Seq
+
+#### Librispeech Seq2Seq
+
+- [Librispeech](https://huggingface.co/datasets/librispeech_asr)
+
+| Dataset | Dataset Config | Pretrained Model | Word error rate on eval | Phoneme error rate on eval | GPU setup | Training time | Fine-tuned Model & Logs | Command to reproduce |
+|----------------------------------------------------------------|---------------------------|-----------------------------------------------------------------------------------------------------------------------------------------------------------|-------------------------|----------------------------|------------|---------------|-----------------------------------------------------------------------|-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
+| [Librispeech](https://huggingface.co/datasets/librispeech_asr) | `"clean"` - `"train.100"` | [facebook/wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base) and [facebook/bart-base](https://huggingface.co/facebook/bart-base) | 0.0728 | - | 8 GPU V100 | 45min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-2-bart-base) | [create_model.py](https://huggingface.co/patrickvonplaten/wav2vec2-2-bart-base/blob/main/create_model.py) & [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-2-bart-base/blob/main/run_librispeech.sh) |
+| [Librispeech](https://huggingface.co/datasets/librispeech_asr) | `"clean"` - `"train.100"` | [facebook/wav2vec2-large-lv60](https://huggingface.co/facebook/wav2vec2-large-lv60) and [facebook/bart-large](https://huggingface.co/facebook/bart-large) | 0.0486 | - | 8 GPU V100 | 1h20min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-2-bart-large) | [create_model.py](https://huggingface.co/patrickvonplaten/wav2vec2-2-bart-large/blob/main/create_model.py) & [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-2-bart-large/blob/main/run_librispeech.sh) |
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-recognition/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-recognition/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..a16697b038c6350b32ee9e35b6fd6331ee1e26da
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-recognition/requirements.txt
@@ -0,0 +1,6 @@
+datasets >= 1.18.0
+torch >= 1.5
+torchaudio
+librosa
+jiwer
+evaluate
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-recognition/run_speech_recognition_ctc.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-recognition/run_speech_recognition_ctc.py
new file mode 100644
index 0000000000000000000000000000000000000000..70fc035fabb84515c9aba6cb0814d0d3c57f1ae4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-recognition/run_speech_recognition_ctc.py
@@ -0,0 +1,822 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""Fine-tuning a 🤗 Transformers CTC model for automatic speech recognition"""
+
+import functools
+import json
+import logging
+import os
+import re
+import sys
+import warnings
+from dataclasses import dataclass, field
+from typing import Dict, List, Optional, Union
+
+import datasets
+import evaluate
+import torch
+from datasets import DatasetDict, load_dataset
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoFeatureExtractor,
+ AutoModelForCTC,
+ AutoProcessor,
+ AutoTokenizer,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ Wav2Vec2Processor,
+ set_seed,
+)
+from transformers.trainer_utils import get_last_checkpoint, is_main_process
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.18.0", "To fix: pip install -r examples/pytorch/speech-recognition/requirements.txt")
+
+
+logger = logging.getLogger(__name__)
+
+
+def list_field(default=None, metadata=None):
+ return field(default_factory=lambda: default, metadata=metadata)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ tokenizer_name_or_path: Optional[str] = field(
+ default=None,
+ metadata={"help": "Path to pretrained tokenizer or tokenizer identifier from huggingface.co/models"},
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+ freeze_feature_encoder: bool = field(
+ default=True, metadata={"help": "Whether to freeze the feature encoder layers of the model."}
+ )
+ attention_dropout: float = field(
+ default=0.0, metadata={"help": "The dropout ratio for the attention probabilities."}
+ )
+ activation_dropout: float = field(
+ default=0.0, metadata={"help": "The dropout ratio for activations inside the fully connected layer."}
+ )
+ feat_proj_dropout: float = field(default=0.0, metadata={"help": "The dropout ratio for the projected features."})
+ hidden_dropout: float = field(
+ default=0.0,
+ metadata={
+ "help": "The dropout probability for all fully connected layers in the embeddings, encoder, and pooler."
+ },
+ )
+ final_dropout: float = field(
+ default=0.0,
+ metadata={"help": "The dropout probability for the final projection layer."},
+ )
+ mask_time_prob: float = field(
+ default=0.05,
+ metadata={
+ "help": (
+ "Probability of each feature vector along the time axis to be chosen as the start of the vector "
+ "span to be masked. Approximately ``mask_time_prob * sequence_length // mask_time_length`` feature "
+ "vectors will be masked along the time axis."
+ )
+ },
+ )
+ mask_time_length: int = field(
+ default=10,
+ metadata={"help": "Length of vector span to mask along the time axis."},
+ )
+ mask_feature_prob: float = field(
+ default=0.0,
+ metadata={
+ "help": (
+ "Probability of each feature vector along the feature axis to be chosen as the start of the vectorspan"
+ " to be masked. Approximately ``mask_feature_prob * sequence_length // mask_feature_length`` feature"
+ " bins will be masked along the time axis."
+ )
+ },
+ )
+ mask_feature_length: int = field(
+ default=10,
+ metadata={"help": "Length of vector span to mask along the feature axis."},
+ )
+ layerdrop: float = field(default=0.0, metadata={"help": "The LayerDrop probability."})
+ ctc_loss_reduction: Optional[str] = field(
+ default="mean", metadata={"help": "The way the ctc loss should be reduced. Should be one of 'mean' or 'sum'."}
+ )
+ ctc_zero_infinity: Optional[bool] = field(
+ default=False,
+ metadata={
+ "help": "Whether to zero infinite losses and the associated gradients of `torch.nn.CTCLoss`. Infinite losses mainly"
+ " occur when the inputs are too short to be aligned to the targets."
+ },
+ )
+ add_adapter: Optional[bool] = field(
+ default=False,
+ metadata={
+ "help": "Whether a convolutional attention network should be stacked on top of the Wav2Vec2Bert Encoder. Can be very"
+ "useful to downsample the output length."
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+
+ Using `HfArgumentParser` we can turn this class
+ into argparse arguments to be able to specify them on
+ the command line.
+ """
+
+ dataset_name: str = field(
+ metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: str = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_split_name: str = field(
+ default="train+validation",
+ metadata={
+ "help": (
+ "The name of the training data set split to use (via the datasets library). Defaults to "
+ "'train+validation'"
+ )
+ },
+ )
+ eval_split_name: str = field(
+ default="test",
+ metadata={
+ "help": "The name of the evaluation data set split to use (via the datasets library). Defaults to 'test'"
+ },
+ )
+ audio_column_name: str = field(
+ default="audio",
+ metadata={"help": "The name of the dataset column containing the audio data. Defaults to 'audio'"},
+ )
+ text_column_name: str = field(
+ default="text",
+ metadata={"help": "The name of the dataset column containing the text data. Defaults to 'text'"},
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached preprocessed datasets or not."}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of validation examples to this "
+ "value if set."
+ )
+ },
+ )
+ chars_to_ignore: Optional[List[str]] = list_field(
+ default=None,
+ metadata={"help": "A list of characters to remove from the transcripts."},
+ )
+ eval_metrics: List[str] = list_field(
+ default=["wer"],
+ metadata={"help": "A list of metrics the model should be evaluated on. E.g. `'wer cer'`"},
+ )
+ max_duration_in_seconds: float = field(
+ default=20.0,
+ metadata={
+ "help": (
+ "Filter audio files that are longer than `max_duration_in_seconds` seconds to"
+ " 'max_duration_in_seconds`"
+ )
+ },
+ )
+ min_duration_in_seconds: float = field(
+ default=0.0, metadata={"help": "Filter audio files that are shorter than `min_duration_in_seconds` seconds"}
+ )
+ preprocessing_only: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to only do data preprocessing and skip training. This is especially useful when data"
+ " preprocessing errors out in distributed training due to timeout. In this case, one should run the"
+ " preprocessing in a non-distributed setup with `preprocessing_only=True` so that the cached datasets"
+ " can consequently be loaded in distributed training"
+ )
+ },
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ unk_token: str = field(
+ default="[UNK]",
+ metadata={"help": "The unk token for the tokenizer"},
+ )
+ pad_token: str = field(
+ default="[PAD]",
+ metadata={"help": "The padding token for the tokenizer"},
+ )
+ word_delimiter_token: str = field(
+ default="|",
+ metadata={"help": "The word delimiter token for the tokenizer"},
+ )
+ phoneme_language: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The target language that should be used be"
+ " passed to the tokenizer for tokenization. Note that"
+ " this is only relevant if the model classifies the"
+ " input audio to a sequence of phoneme sequences."
+ )
+ },
+ )
+
+
+@dataclass
+class DataCollatorCTCWithPadding:
+ """
+ Data collator that will dynamically pad the inputs received.
+ Args:
+ processor (:class:`~transformers.AutoProcessor`)
+ The processor used for proccessing the data.
+ padding (:obj:`bool`, :obj:`str` or :class:`~transformers.tokenization_utils_base.PaddingStrategy`, `optional`, defaults to :obj:`True`):
+ Select a strategy to pad the returned sequences (according to the model's padding side and padding index)
+ among:
+ * :obj:`True` or :obj:`'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
+ sequence if provided).
+ * :obj:`'max_length'`: Pad to a maximum length specified with the argument :obj:`max_length` or to the
+ maximum acceptable input length for the model if that argument is not provided.
+ * :obj:`False` or :obj:`'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of
+ different lengths).
+ max_length (:obj:`int`, `optional`):
+ Maximum length of the ``input_values`` of the returned list and optionally padding length (see above).
+ max_length_labels (:obj:`int`, `optional`):
+ Maximum length of the ``labels`` returned list and optionally padding length (see above).
+ pad_to_multiple_of (:obj:`int`, `optional`):
+ If set will pad the sequence to a multiple of the provided value.
+ This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability >=
+ 7.5 (Volta).
+ """
+
+ processor: AutoProcessor
+ padding: Union[bool, str] = "longest"
+ pad_to_multiple_of: Optional[int] = None
+ pad_to_multiple_of_labels: Optional[int] = None
+ feature_extractor_input_name: Optional[str] = "input_values"
+
+ def __call__(self, features: List[Dict[str, Union[List[int], torch.Tensor]]]) -> Dict[str, torch.Tensor]:
+ # split inputs and labels since they have to be of different lengths and need
+ # different padding methods
+ input_features = [
+ {self.feature_extractor_input_name: feature[self.feature_extractor_input_name]} for feature in features
+ ]
+ label_features = [{"input_ids": feature["labels"]} for feature in features]
+
+ batch = self.processor.pad(
+ input_features,
+ padding=self.padding,
+ pad_to_multiple_of=self.pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ labels_batch = self.processor.pad(
+ labels=label_features,
+ padding=self.padding,
+ pad_to_multiple_of=self.pad_to_multiple_of_labels,
+ return_tensors="pt",
+ )
+
+ # replace padding with -100 to ignore loss correctly
+ labels = labels_batch["input_ids"].masked_fill(labels_batch.attention_mask.ne(1), -100)
+
+ batch["labels"] = labels
+ if "attention_mask" in batch:
+ batch["attention_mask"] = batch["attention_mask"].to(torch.long)
+
+ return batch
+
+
+def create_vocabulary_from_data(
+ datasets: DatasetDict,
+ word_delimiter_token: Optional[str] = None,
+ unk_token: Optional[str] = None,
+ pad_token: Optional[str] = None,
+):
+ # Given training and test labels create vocabulary
+ def extract_all_chars(batch):
+ all_text = " ".join(batch["target_text"])
+ vocab = list(set(all_text))
+ return {"vocab": [vocab], "all_text": [all_text]}
+
+ vocabs = datasets.map(
+ extract_all_chars,
+ batched=True,
+ batch_size=-1,
+ keep_in_memory=True,
+ remove_columns=datasets["train"].column_names,
+ )
+
+ # take union of all unique characters in each dataset
+ vocab_set = functools.reduce(
+ lambda vocab_1, vocab_2: set(vocab_1["vocab"][0]) | set(vocab_2["vocab"][0]), vocabs.values()
+ )
+
+ vocab_dict = {v: k for k, v in enumerate(sorted(vocab_set))}
+
+ # replace white space with delimiter token
+ if word_delimiter_token is not None:
+ vocab_dict[word_delimiter_token] = vocab_dict[" "]
+ del vocab_dict[" "]
+
+ # add unk and pad token
+ if unk_token is not None:
+ vocab_dict[unk_token] = len(vocab_dict)
+
+ if pad_token is not None:
+ vocab_dict[pad_token] = len(vocab_dict)
+
+ return vocab_dict
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_speech_recognition_ctc", model_args, data_args)
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+ logger.setLevel(logging.INFO if is_main_process(training_args.local_rank) else logging.WARN)
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ if is_main_process(training_args.local_rank):
+ transformers.utils.logging.set_verbosity_info()
+ logger.info("Training/evaluation parameters %s", training_args)
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # 1. First, let's load the dataset
+ raw_datasets = DatasetDict()
+
+ if training_args.do_train:
+ raw_datasets["train"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=data_args.train_split_name,
+ token=data_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+
+ if data_args.audio_column_name not in raw_datasets["train"].column_names:
+ raise ValueError(
+ f"--audio_column_name '{data_args.audio_column_name}' not found in dataset '{data_args.dataset_name}'."
+ " Make sure to set `--audio_column_name` to the correct audio column - one of"
+ f" {', '.join(raw_datasets['train'].column_names)}."
+ )
+
+ if data_args.text_column_name not in raw_datasets["train"].column_names:
+ raise ValueError(
+ f"--text_column_name {data_args.text_column_name} not found in dataset '{data_args.dataset_name}'. "
+ "Make sure to set `--text_column_name` to the correct text column - one of "
+ f"{', '.join(raw_datasets['train'].column_names)}."
+ )
+
+ if data_args.max_train_samples is not None:
+ raw_datasets["train"] = raw_datasets["train"].select(range(data_args.max_train_samples))
+
+ if training_args.do_eval:
+ raw_datasets["eval"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=data_args.eval_split_name,
+ token=data_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+
+ if data_args.max_eval_samples is not None:
+ raw_datasets["eval"] = raw_datasets["eval"].select(range(data_args.max_eval_samples))
+
+ # 2. We remove some special characters from the datasets
+ # that make training complicated and do not help in transcribing the speech
+ # E.g. characters, such as `,` and `.` do not really have an acoustic characteristic
+ # that could be easily picked up by the model
+ chars_to_ignore_regex = (
+ f'[{"".join(data_args.chars_to_ignore)}]' if data_args.chars_to_ignore is not None else None
+ )
+ text_column_name = data_args.text_column_name
+
+ def remove_special_characters(batch):
+ if chars_to_ignore_regex is not None:
+ batch["target_text"] = re.sub(chars_to_ignore_regex, "", batch[text_column_name]).lower() + " "
+ else:
+ batch["target_text"] = batch[text_column_name].lower() + " "
+ return batch
+
+ with training_args.main_process_first(desc="dataset map special characters removal"):
+ raw_datasets = raw_datasets.map(
+ remove_special_characters,
+ remove_columns=[text_column_name],
+ desc="remove special characters from datasets",
+ )
+
+ # save special tokens for tokenizer
+ word_delimiter_token = data_args.word_delimiter_token
+ unk_token = data_args.unk_token
+ pad_token = data_args.pad_token
+
+ # 3. Next, let's load the config as we might need it to create
+ # the tokenizer
+ # load config
+ config = AutoConfig.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ token=data_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+
+ # 4. Next, if no tokenizer file is defined,
+ # we create the vocabulary of the model by extracting all unique characters from
+ # the training and evaluation datasets
+ # We need to make sure that only first rank saves vocabulary
+ # make sure all processes wait until vocab is created
+ tokenizer_name_or_path = model_args.tokenizer_name_or_path
+ tokenizer_kwargs = {}
+ if tokenizer_name_or_path is None:
+ # save vocab in training output dir
+ tokenizer_name_or_path = training_args.output_dir
+
+ vocab_file = os.path.join(tokenizer_name_or_path, "vocab.json")
+
+ with training_args.main_process_first():
+ if training_args.overwrite_output_dir and os.path.isfile(vocab_file):
+ try:
+ os.remove(vocab_file)
+ except OSError:
+ # in shared file-systems it might be the case that
+ # two processes try to delete the vocab file at the some time
+ pass
+
+ with training_args.main_process_first(desc="dataset map vocabulary creation"):
+ if not os.path.isfile(vocab_file):
+ os.makedirs(tokenizer_name_or_path, exist_ok=True)
+ vocab_dict = create_vocabulary_from_data(
+ raw_datasets,
+ word_delimiter_token=word_delimiter_token,
+ unk_token=unk_token,
+ pad_token=pad_token,
+ )
+
+ # save vocab dict to be loaded into tokenizer
+ with open(vocab_file, "w") as file:
+ json.dump(vocab_dict, file)
+
+ # if tokenizer has just been created
+ # it is defined by `tokenizer_class` if present in config else by `model_type`
+ tokenizer_kwargs = {
+ "config": config if config.tokenizer_class is not None else None,
+ "tokenizer_type": config.model_type if config.tokenizer_class is None else None,
+ "unk_token": unk_token,
+ "pad_token": pad_token,
+ "word_delimiter_token": word_delimiter_token,
+ }
+
+ # 5. Now we can instantiate the feature extractor, tokenizer and model
+ # Note for distributed training, the .from_pretrained methods guarantee that only
+ # one local process can concurrently download model & vocab.
+
+ # load feature_extractor and tokenizer
+ tokenizer = AutoTokenizer.from_pretrained(
+ tokenizer_name_or_path,
+ token=data_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ **tokenizer_kwargs,
+ )
+ feature_extractor = AutoFeatureExtractor.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ token=data_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+
+ # adapt config
+ config.update(
+ {
+ "feat_proj_dropout": model_args.feat_proj_dropout,
+ "attention_dropout": model_args.attention_dropout,
+ "hidden_dropout": model_args.hidden_dropout,
+ "final_dropout": model_args.final_dropout,
+ "mask_time_prob": model_args.mask_time_prob,
+ "mask_time_length": model_args.mask_time_length,
+ "mask_feature_prob": model_args.mask_feature_prob,
+ "mask_feature_length": model_args.mask_feature_length,
+ "gradient_checkpointing": training_args.gradient_checkpointing,
+ "layerdrop": model_args.layerdrop,
+ "ctc_loss_reduction": model_args.ctc_loss_reduction,
+ "ctc_zero_infinity": model_args.ctc_zero_infinity,
+ "pad_token_id": tokenizer.pad_token_id,
+ "vocab_size": len(tokenizer),
+ "activation_dropout": model_args.activation_dropout,
+ "add_adapter": model_args.add_adapter,
+ }
+ )
+
+ # create model
+ model = AutoModelForCTC.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ config=config,
+ token=data_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+
+ # freeze encoder
+ if model_args.freeze_feature_encoder:
+ model.freeze_feature_encoder()
+
+ # 6. Now we preprocess the datasets including loading the audio, resampling and normalization
+ # Thankfully, `datasets` takes care of automatically loading and resampling the audio,
+ # so that we just need to set the correct target sampling rate and normalize the input
+ # via the `feature_extractor`
+
+ # make sure that dataset decodes audio with correct sampling rate
+ dataset_sampling_rate = next(iter(raw_datasets.values())).features[data_args.audio_column_name].sampling_rate
+ if dataset_sampling_rate != feature_extractor.sampling_rate:
+ raw_datasets = raw_datasets.cast_column(
+ data_args.audio_column_name, datasets.features.Audio(sampling_rate=feature_extractor.sampling_rate)
+ )
+
+ # derive max & min input length for sample rate & max duration
+ max_input_length = data_args.max_duration_in_seconds * feature_extractor.sampling_rate
+ min_input_length = data_args.min_duration_in_seconds * feature_extractor.sampling_rate
+ audio_column_name = data_args.audio_column_name
+ num_workers = data_args.preprocessing_num_workers
+ feature_extractor_input_name = feature_extractor.model_input_names[0]
+
+ # `phoneme_language` is only relevant if the model is fine-tuned on phoneme classification
+ phoneme_language = data_args.phoneme_language
+
+ # Preprocessing the datasets.
+ # We need to read the audio files as arrays and tokenize the targets.
+ def prepare_dataset(batch):
+ # load audio
+ sample = batch[audio_column_name]
+
+ inputs = feature_extractor(sample["array"], sampling_rate=sample["sampling_rate"])
+ batch[feature_extractor_input_name] = getattr(inputs, feature_extractor_input_name)[0]
+ # take length of raw audio waveform
+ batch["input_length"] = len(sample["array"].squeeze())
+
+ # encode targets
+ additional_kwargs = {}
+ if phoneme_language is not None:
+ additional_kwargs["phonemizer_lang"] = phoneme_language
+
+ batch["labels"] = tokenizer(batch["target_text"], **additional_kwargs).input_ids
+ return batch
+
+ with training_args.main_process_first(desc="dataset map preprocessing"):
+ vectorized_datasets = raw_datasets.map(
+ prepare_dataset,
+ remove_columns=next(iter(raw_datasets.values())).column_names,
+ num_proc=num_workers,
+ desc="preprocess datasets",
+ )
+
+ def is_audio_in_length_range(length):
+ return length > min_input_length and length < max_input_length
+
+ # filter data that is shorter than min_input_length
+ vectorized_datasets = vectorized_datasets.filter(
+ is_audio_in_length_range,
+ num_proc=num_workers,
+ input_columns=["input_length"],
+ )
+
+ # 7. Next, we can prepare the training.
+ # Let's use word error rate (WER) as our evaluation metric,
+ # instantiate a data collator and the trainer
+
+ # Define evaluation metrics during training, *i.e.* word error rate, character error rate
+ eval_metrics = {metric: evaluate.load(metric, cache_dir=model_args.cache_dir) for metric in data_args.eval_metrics}
+
+ # for large datasets it is advised to run the preprocessing on a
+ # single machine first with ``args.preprocessing_only`` since there will mostly likely
+ # be a timeout when running the script in distributed mode.
+ # In a second step ``args.preprocessing_only`` can then be set to `False` to load the
+ # cached dataset
+ if data_args.preprocessing_only:
+ logger.info(f"Data preprocessing finished. Files cached at {vectorized_datasets.cache_files}")
+ return
+
+ # For languages like Chinese with large vocabulary size, we need to discard logits
+ # and only keep the argmax, otherwise we run out of memory during evaluation.
+ def preprocess_logits_for_metrics(logits, labels):
+ pred_ids = torch.argmax(logits, dim=-1)
+ return pred_ids, labels
+
+ def compute_metrics(pred):
+ pred_ids = pred.predictions[0]
+ pred.label_ids[pred.label_ids == -100] = tokenizer.pad_token_id
+
+ pred_str = tokenizer.batch_decode(pred_ids)
+ # we do not want to group tokens when computing the metrics
+ label_str = tokenizer.batch_decode(pred.label_ids, group_tokens=False)
+
+ metrics = {k: v.compute(predictions=pred_str, references=label_str) for k, v in eval_metrics.items()}
+
+ return metrics
+
+ # Now save everything to be able to create a single processor later
+ # make sure all processes wait until data is saved
+ with training_args.main_process_first():
+ # only the main process saves them
+ if is_main_process(training_args.local_rank):
+ # save feature extractor, tokenizer and config
+ feature_extractor.save_pretrained(training_args.output_dir)
+ tokenizer.save_pretrained(training_args.output_dir)
+ config.save_pretrained(training_args.output_dir)
+
+ try:
+ processor = AutoProcessor.from_pretrained(training_args.output_dir)
+ except (OSError, KeyError):
+ warnings.warn(
+ "Loading a processor from a feature extractor config that does not"
+ " include a `processor_class` attribute is deprecated and will be removed in v5. Please add the following "
+ " attribute to your `preprocessor_config.json` file to suppress this warning: "
+ " `'processor_class': 'Wav2Vec2Processor'`",
+ FutureWarning,
+ )
+ processor = Wav2Vec2Processor.from_pretrained(training_args.output_dir)
+
+ # Instantiate custom data collator
+ data_collator = DataCollatorCTCWithPadding(
+ processor=processor, feature_extractor_input_name=feature_extractor_input_name
+ )
+
+ # Initialize Trainer
+ trainer = Trainer(
+ model=model,
+ data_collator=data_collator,
+ args=training_args,
+ compute_metrics=compute_metrics,
+ train_dataset=vectorized_datasets["train"] if training_args.do_train else None,
+ eval_dataset=vectorized_datasets["eval"] if training_args.do_eval else None,
+ processing_class=processor,
+ preprocess_logits_for_metrics=preprocess_logits_for_metrics,
+ )
+
+ # 8. Finally, we can start training
+
+ # Training
+ if training_args.do_train:
+ # use last checkpoint if exist
+ if last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ elif os.path.isdir(model_args.model_name_or_path):
+ checkpoint = model_args.model_name_or_path
+ else:
+ checkpoint = None
+
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model()
+
+ metrics = train_result.metrics
+ max_train_samples = (
+ data_args.max_train_samples
+ if data_args.max_train_samples is not None
+ else len(vectorized_datasets["train"])
+ )
+ metrics["train_samples"] = min(max_train_samples, len(vectorized_datasets["train"]))
+
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ results = {}
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+ metrics = trainer.evaluate()
+ max_eval_samples = (
+ data_args.max_eval_samples if data_args.max_eval_samples is not None else len(vectorized_datasets["eval"])
+ )
+ metrics["eval_samples"] = min(max_eval_samples, len(vectorized_datasets["eval"]))
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ # Write model card and (optionally) push to hub
+ config_name = data_args.dataset_config_name if data_args.dataset_config_name is not None else "na"
+ kwargs = {
+ "finetuned_from": model_args.model_name_or_path,
+ "tasks": "automatic-speech-recognition",
+ "tags": ["automatic-speech-recognition", data_args.dataset_name],
+ "dataset_args": (
+ f"Config: {config_name}, Training split: {data_args.train_split_name}, Eval split:"
+ f" {data_args.eval_split_name}"
+ ),
+ "dataset": f"{data_args.dataset_name.upper()} - {config_name.upper()}",
+ }
+ if "common_voice" in data_args.dataset_name:
+ kwargs["language"] = config_name
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+ return results
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-recognition/run_speech_recognition_ctc_adapter.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-recognition/run_speech_recognition_ctc_adapter.py
new file mode 100644
index 0000000000000000000000000000000000000000..a6e3d9f7f33fc05ea7e8e908a1c0e5069b62674d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-recognition/run_speech_recognition_ctc_adapter.py
@@ -0,0 +1,823 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2023 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""Fine-tuning a 🤗 Transformers CTC adapter model for automatic speech recognition"""
+
+import functools
+import json
+import logging
+import os
+import re
+import sys
+import warnings
+from dataclasses import dataclass, field
+from typing import Dict, List, Optional, Union
+
+import datasets
+import evaluate
+import numpy as np
+import torch
+from datasets import DatasetDict, load_dataset
+from safetensors.torch import save_file as safe_save_file
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoFeatureExtractor,
+ AutoModelForCTC,
+ AutoProcessor,
+ AutoTokenizer,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ Wav2Vec2Processor,
+ set_seed,
+)
+from transformers.models.wav2vec2.modeling_wav2vec2 import WAV2VEC2_ADAPTER_SAFE_FILE
+from transformers.trainer_utils import get_last_checkpoint, is_main_process
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.18.0", "To fix: pip install -r examples/pytorch/speech-recognition/requirements.txt")
+
+
+logger = logging.getLogger(__name__)
+
+
+def list_field(default=None, metadata=None):
+ return field(default_factory=lambda: default, metadata=metadata)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ tokenizer_name_or_path: Optional[str] = field(
+ default=None,
+ metadata={"help": "Path to pretrained tokenizer or tokenizer identifier from huggingface.co/models"},
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+ final_dropout: float = field(
+ default=0.0,
+ metadata={"help": "The dropout probability for the final projection layer."},
+ )
+ mask_time_prob: float = field(
+ default=0.05,
+ metadata={
+ "help": (
+ "Probability of each feature vector along the time axis to be chosen as the start of the vector "
+ "span to be masked. Approximately ``mask_time_prob * sequence_length // mask_time_length`` feature "
+ "vectors will be masked along the time axis."
+ )
+ },
+ )
+ mask_time_length: int = field(
+ default=10,
+ metadata={"help": "Length of vector span to mask along the time axis."},
+ )
+ mask_feature_prob: float = field(
+ default=0.0,
+ metadata={
+ "help": (
+ "Probability of each feature vector along the feature axis to be chosen as the start of the vectorspan"
+ " to be masked. Approximately ``mask_feature_prob * sequence_length // mask_feature_length`` feature"
+ " bins will be masked along the time axis."
+ )
+ },
+ )
+ mask_feature_length: int = field(
+ default=10,
+ metadata={"help": "Length of vector span to mask along the feature axis."},
+ )
+ layerdrop: float = field(default=0.0, metadata={"help": "The LayerDrop probability."})
+ ctc_loss_reduction: Optional[str] = field(
+ default="mean", metadata={"help": "The way the ctc loss should be reduced. Should be one of 'mean' or 'sum'."}
+ )
+ adapter_attn_dim: int = field(
+ default=16,
+ metadata={
+ "help": "The hidden dimension of the adapter layers that will be randomly initialized and trained. The higher the dimension, the more capacity is given to the adapter weights. Note that only the adapter weights are fine-tuned."
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+
+ Using `HfArgumentParser` we can turn this class
+ into argparse arguments to be able to specify them on
+ the command line.
+ """
+
+ dataset_name: str = field(
+ metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ target_language: Optional[str] = field(
+ metadata={
+ "help": (
+ "The target language on which the adapter attention layers"
+ " should be trained on in ISO 693-3 code, e.g. `tur` for Turkish"
+ " Wav2Vec2's MMS ISO codes can be looked up here: https://dl.fbaipublicfiles.com/mms/misc/language_coverage_mms.html"
+ " If you are not training the adapter layers on a language, simply choose"
+ " another acronym that fits your data."
+ )
+ },
+ )
+ dataset_config_name: str = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_split_name: str = field(
+ default="train+validation",
+ metadata={
+ "help": (
+ "The name of the training data set split to use (via the datasets library). Defaults to "
+ "'train+validation'"
+ )
+ },
+ )
+ eval_split_name: str = field(
+ default="test",
+ metadata={
+ "help": "The name of the evaluation data set split to use (via the datasets library). Defaults to 'test'"
+ },
+ )
+ audio_column_name: str = field(
+ default="audio",
+ metadata={"help": "The name of the dataset column containing the audio data. Defaults to 'audio'"},
+ )
+ text_column_name: str = field(
+ default="text",
+ metadata={"help": "The name of the dataset column containing the text data. Defaults to 'text'"},
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached preprocessed datasets or not."}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of validation examples to this "
+ "value if set."
+ )
+ },
+ )
+ chars_to_ignore: Optional[List[str]] = list_field(
+ default=None,
+ metadata={"help": "A list of characters to remove from the transcripts."},
+ )
+ eval_metrics: List[str] = list_field(
+ default=["wer"],
+ metadata={"help": "A list of metrics the model should be evaluated on. E.g. `'wer cer'`"},
+ )
+ max_duration_in_seconds: float = field(
+ default=20.0,
+ metadata={
+ "help": (
+ "Filter audio files that are longer than `max_duration_in_seconds` seconds to"
+ " 'max_duration_in_seconds`"
+ )
+ },
+ )
+ min_duration_in_seconds: float = field(
+ default=0.0, metadata={"help": "Filter audio files that are shorter than `min_duration_in_seconds` seconds"}
+ )
+ preprocessing_only: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to only do data preprocessing and skip training. This is especially useful when data"
+ " preprocessing errors out in distributed training due to timeout. In this case, one should run the"
+ " preprocessing in a non-distributed setup with `preprocessing_only=True` so that the cached datasets"
+ " can consequently be loaded in distributed training"
+ )
+ },
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ unk_token: str = field(
+ default="[UNK]",
+ metadata={"help": "The unk token for the tokenizer"},
+ )
+ pad_token: str = field(
+ default="[PAD]",
+ metadata={"help": "The padding token for the tokenizer"},
+ )
+ word_delimiter_token: str = field(
+ default="|",
+ metadata={"help": "The word delimiter token for the tokenizer"},
+ )
+ overwrite_lang_vocab: bool = field(
+ default=False,
+ metadata={"help": ("If :obj:`True`, will overwrite existing `target_language` vocabulary of tokenizer.")},
+ )
+
+
+@dataclass
+class DataCollatorCTCWithPadding:
+ """
+ Data collator that will dynamically pad the inputs received.
+ Args:
+ processor (:class:`~transformers.AutoProcessor`)
+ The processor used for proccessing the data.
+ padding (:obj:`bool`, :obj:`str` or :class:`~transformers.tokenization_utils_base.PaddingStrategy`, `optional`, defaults to :obj:`True`):
+ Select a strategy to pad the returned sequences (according to the model's padding side and padding index)
+ among:
+ * :obj:`True` or :obj:`'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
+ sequence if provided).
+ * :obj:`'max_length'`: Pad to a maximum length specified with the argument :obj:`max_length` or to the
+ maximum acceptable input length for the model if that argument is not provided.
+ * :obj:`False` or :obj:`'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of
+ different lengths).
+ max_length (:obj:`int`, `optional`):
+ Maximum length of the ``input_values`` of the returned list and optionally padding length (see above).
+ max_length_labels (:obj:`int`, `optional`):
+ Maximum length of the ``labels`` returned list and optionally padding length (see above).
+ pad_to_multiple_of (:obj:`int`, `optional`):
+ If set will pad the sequence to a multiple of the provided value.
+ This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability >=
+ 7.5 (Volta).
+ """
+
+ processor: AutoProcessor
+ padding: Union[bool, str] = "longest"
+ pad_to_multiple_of: Optional[int] = None
+ pad_to_multiple_of_labels: Optional[int] = None
+
+ def __call__(self, features: List[Dict[str, Union[List[int], torch.Tensor]]]) -> Dict[str, torch.Tensor]:
+ # split inputs and labels since they have to be of different lengths and need
+ # different padding methods
+ input_features = [{"input_values": feature["input_values"]} for feature in features]
+ label_features = [{"input_ids": feature["labels"]} for feature in features]
+
+ batch = self.processor.pad(
+ input_features,
+ padding=self.padding,
+ pad_to_multiple_of=self.pad_to_multiple_of,
+ return_tensors="pt",
+ )
+
+ labels_batch = self.processor.pad(
+ labels=label_features,
+ padding=self.padding,
+ pad_to_multiple_of=self.pad_to_multiple_of_labels,
+ return_tensors="pt",
+ )
+
+ # replace padding with -100 to ignore loss correctly
+ labels = labels_batch["input_ids"].masked_fill(labels_batch.attention_mask.ne(1), -100)
+
+ batch["labels"] = labels
+ if "attention_mask" in batch:
+ batch["attention_mask"] = batch["attention_mask"].to(torch.long)
+
+ return batch
+
+
+def create_vocabulary_from_data(
+ datasets: DatasetDict,
+ word_delimiter_token: Optional[str] = None,
+ unk_token: Optional[str] = None,
+ pad_token: Optional[str] = None,
+):
+ # Given training and test labels create vocabulary
+ def extract_all_chars(batch):
+ all_text = " ".join(batch["target_text"])
+ vocab = list(set(all_text))
+ return {"vocab": [vocab], "all_text": [all_text]}
+
+ vocabs = datasets.map(
+ extract_all_chars,
+ batched=True,
+ batch_size=-1,
+ keep_in_memory=True,
+ remove_columns=datasets["train"].column_names,
+ )
+
+ # take union of all unique characters in each dataset
+ vocab_set = functools.reduce(
+ lambda vocab_1, vocab_2: set(vocab_1["vocab"][0]) | set(vocab_2["vocab"][0]), vocabs.values()
+ )
+
+ vocab_dict = {v: k for k, v in enumerate(sorted(vocab_set))}
+
+ # replace white space with delimiter token
+ if word_delimiter_token is not None:
+ vocab_dict[word_delimiter_token] = vocab_dict[" "]
+ del vocab_dict[" "]
+
+ # add unk and pad token
+ if unk_token is not None:
+ vocab_dict[unk_token] = len(vocab_dict)
+
+ if pad_token is not None:
+ vocab_dict[pad_token] = len(vocab_dict)
+
+ return vocab_dict
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_speech_recognition_ctc_adapter", model_args, data_args)
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+ logger.setLevel(logging.INFO if is_main_process(training_args.local_rank) else logging.WARN)
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ if is_main_process(training_args.local_rank):
+ transformers.utils.logging.set_verbosity_info()
+ logger.info("Training/evaluation parameters %s", training_args)
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # 1. First, let's load the dataset
+ raw_datasets = DatasetDict()
+
+ if training_args.do_train:
+ raw_datasets["train"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=data_args.train_split_name,
+ token=data_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+
+ if data_args.audio_column_name not in raw_datasets["train"].column_names:
+ raise ValueError(
+ f"--audio_column_name '{data_args.audio_column_name}' not found in dataset '{data_args.dataset_name}'."
+ " Make sure to set `--audio_column_name` to the correct audio column - one of"
+ f" {', '.join(raw_datasets['train'].column_names)}."
+ )
+
+ if data_args.text_column_name not in raw_datasets["train"].column_names:
+ raise ValueError(
+ f"--text_column_name {data_args.text_column_name} not found in dataset '{data_args.dataset_name}'. "
+ "Make sure to set `--text_column_name` to the correct text column - one of "
+ f"{', '.join(raw_datasets['train'].column_names)}."
+ )
+
+ if data_args.max_train_samples is not None:
+ raw_datasets["train"] = raw_datasets["train"].select(range(data_args.max_train_samples))
+
+ if training_args.do_eval:
+ raw_datasets["eval"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=data_args.eval_split_name,
+ token=data_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+
+ if data_args.max_eval_samples is not None:
+ raw_datasets["eval"] = raw_datasets["eval"].select(range(data_args.max_eval_samples))
+
+ # 2. We remove some special characters from the datasets
+ # that make training complicated and do not help in transcribing the speech
+ # E.g. characters, such as `,` and `.` do not really have an acoustic characteristic
+ # that could be easily picked up by the model
+ chars_to_ignore_regex = (
+ f'[{"".join(data_args.chars_to_ignore)}]' if data_args.chars_to_ignore is not None else None
+ )
+ text_column_name = data_args.text_column_name
+
+ def remove_special_characters(batch):
+ if chars_to_ignore_regex is not None:
+ batch["target_text"] = re.sub(chars_to_ignore_regex, "", batch[text_column_name]).lower() + " "
+ else:
+ batch["target_text"] = batch[text_column_name].lower() + " "
+ return batch
+
+ with training_args.main_process_first(desc="dataset map special characters removal"):
+ raw_datasets = raw_datasets.map(
+ remove_special_characters,
+ remove_columns=[text_column_name],
+ desc="remove special characters from datasets",
+ )
+
+ # save special tokens for tokenizer
+ word_delimiter_token = data_args.word_delimiter_token
+ unk_token = data_args.unk_token
+ pad_token = data_args.pad_token
+
+ # 3. Next, let's load the config as we might need it to create
+ # the tokenizer
+ # load config
+ config = AutoConfig.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ token=data_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+
+ # 4. Next, if no tokenizer file is defined,
+ # we create the vocabulary of the model by extracting all unique characters from
+ # the training and evaluation datasets
+ # We need to make sure that only first rank saves vocabulary
+ # make sure all processes wait until vocab is created
+ tokenizer_name_or_path = model_args.tokenizer_name_or_path
+ tokenizer_kwargs = {}
+
+ vocab_dict = {}
+ if tokenizer_name_or_path is not None:
+ # load vocabulary of other adapter languages so that new language can be appended
+ tokenizer = AutoTokenizer.from_pretrained(
+ tokenizer_name_or_path,
+ token=data_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+ vocab_dict = tokenizer.vocab.copy()
+ if tokenizer.target_lang is None:
+ raise ValueError("Make sure to load a multi-lingual tokenizer with a set target language.")
+
+ if data_args.target_language in tokenizer.vocab and not data_args.overwrite_lang_vocab:
+ logger.info(
+ "Adapter language already exists."
+ " Skipping vocabulary creating. If you want to create a new vocabulary"
+ f" for {data_args.target_language} make sure to add '--overwrite_lang_vocab'"
+ )
+ else:
+ tokenizer_name_or_path = None
+
+ if tokenizer_name_or_path is None:
+ # save vocab in training output dir
+ tokenizer_name_or_path = training_args.output_dir
+
+ vocab_file = os.path.join(tokenizer_name_or_path, "vocab.json")
+
+ with training_args.main_process_first():
+ if training_args.overwrite_output_dir and os.path.isfile(vocab_file):
+ try:
+ os.remove(vocab_file)
+ except OSError:
+ # in shared file-systems it might be the case that
+ # two processes try to delete the vocab file at the some time
+ pass
+
+ with training_args.main_process_first(desc="dataset map vocabulary creation"):
+ if not os.path.isfile(vocab_file):
+ os.makedirs(tokenizer_name_or_path, exist_ok=True)
+ lang_dict = create_vocabulary_from_data(
+ raw_datasets,
+ word_delimiter_token=word_delimiter_token,
+ unk_token=unk_token,
+ pad_token=pad_token,
+ )
+
+ # if we doing adapter language training, save
+ # vocab with adpter language
+ if data_args.target_language is not None:
+ vocab_dict[data_args.target_language] = lang_dict
+
+ # save vocab dict to be loaded into tokenizer
+ with open(vocab_file, "w") as file:
+ json.dump(vocab_dict, file)
+
+ # if tokenizer has just been created
+ # it is defined by `tokenizer_class` if present in config else by `model_type`
+ tokenizer_kwargs = {
+ "config": config if config.tokenizer_class is not None else None,
+ "tokenizer_type": config.model_type if config.tokenizer_class is None else None,
+ "unk_token": unk_token,
+ "pad_token": pad_token,
+ "word_delimiter_token": word_delimiter_token,
+ "target_lang": data_args.target_language,
+ }
+
+ # 5. Now we can instantiate the feature extractor, tokenizer and model
+ # Note for distributed training, the .from_pretrained methods guarantee that only
+ # one local process can concurrently download model & vocab.
+
+ # load feature_extractor and tokenizer
+ tokenizer = AutoTokenizer.from_pretrained(
+ tokenizer_name_or_path,
+ token=data_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ **tokenizer_kwargs,
+ )
+ feature_extractor = AutoFeatureExtractor.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ token=data_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ )
+
+ # adapt config
+ config.update(
+ {
+ "final_dropout": model_args.final_dropout,
+ "mask_time_prob": model_args.mask_time_prob,
+ "mask_time_length": model_args.mask_time_length,
+ "mask_feature_prob": model_args.mask_feature_prob,
+ "mask_feature_length": model_args.mask_feature_length,
+ "gradient_checkpointing": training_args.gradient_checkpointing,
+ "layerdrop": model_args.layerdrop,
+ "ctc_loss_reduction": model_args.ctc_loss_reduction,
+ "pad_token_id": tokenizer.pad_token_id,
+ "vocab_size": len(tokenizer),
+ "adapter_attn_dim": model_args.adapter_attn_dim,
+ }
+ )
+
+ # create model
+ model = AutoModelForCTC.from_pretrained(
+ model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ config=config,
+ token=data_args.token,
+ trust_remote_code=data_args.trust_remote_code,
+ ignore_mismatched_sizes=True,
+ )
+
+ # if attn adapter is defined, freeze all non-adapter weights
+ if model.config.adapter_attn_dim is not None:
+ model.init_adapter_layers()
+ # first we freeze the whole base model
+ model.freeze_base_model()
+
+ # next we unfreeze all adapter layers
+ adapter_weights = model._get_adapters()
+ for param in adapter_weights.values():
+ param.requires_grad = True
+
+ # 6. Now we preprocess the datasets including loading the audio, resampling and normalization
+ # Thankfully, `datasets` takes care of automatically loading and resampling the audio,
+ # so that we just need to set the correct target sampling rate and normalize the input
+ # via the `feature_extractor`
+
+ # make sure that dataset decodes audio with correct sampling rate
+ dataset_sampling_rate = next(iter(raw_datasets.values())).features[data_args.audio_column_name].sampling_rate
+ if dataset_sampling_rate != feature_extractor.sampling_rate:
+ raw_datasets = raw_datasets.cast_column(
+ data_args.audio_column_name, datasets.features.Audio(sampling_rate=feature_extractor.sampling_rate)
+ )
+
+ # derive max & min input length for sample rate & max duration
+ max_input_length = data_args.max_duration_in_seconds * feature_extractor.sampling_rate
+ min_input_length = data_args.min_duration_in_seconds * feature_extractor.sampling_rate
+ audio_column_name = data_args.audio_column_name
+ num_workers = data_args.preprocessing_num_workers
+
+ # Preprocessing the datasets.
+ # We need to read the audio files as arrays and tokenize the targets.
+ def prepare_dataset(batch):
+ # load audio
+ sample = batch[audio_column_name]
+
+ inputs = feature_extractor(sample["array"], sampling_rate=sample["sampling_rate"])
+ batch["input_values"] = inputs.input_values[0]
+ batch["input_length"] = len(batch["input_values"])
+
+ # encode targets
+ batch["labels"] = tokenizer(batch["target_text"]).input_ids
+ return batch
+
+ with training_args.main_process_first(desc="dataset map preprocessing"):
+ vectorized_datasets = raw_datasets.map(
+ prepare_dataset,
+ remove_columns=next(iter(raw_datasets.values())).column_names,
+ num_proc=num_workers,
+ desc="preprocess datasets",
+ )
+
+ def is_audio_in_length_range(length):
+ return length > min_input_length and length < max_input_length
+
+ # filter data that is shorter than min_input_length
+ vectorized_datasets = vectorized_datasets.filter(
+ is_audio_in_length_range,
+ num_proc=num_workers,
+ input_columns=["input_length"],
+ )
+
+ # 7. Next, we can prepare the training.
+ # Let's use word error rate (WER) as our evaluation metric,
+ # instantiate a data collator and the trainer
+
+ # Define evaluation metrics during training, *i.e.* word error rate, character error rate
+ eval_metrics = {metric: evaluate.load(metric, cache_dir=model_args.cache_dir) for metric in data_args.eval_metrics}
+
+ # for large datasets it is advised to run the preprocessing on a
+ # single machine first with ``args.preprocessing_only`` since there will mostly likely
+ # be a timeout when running the script in distributed mode.
+ # In a second step ``args.preprocessing_only`` can then be set to `False` to load the
+ # cached dataset
+ if data_args.preprocessing_only:
+ logger.info(f"Data preprocessing finished. Files cached at {vectorized_datasets.cache_files}")
+ return
+
+ def compute_metrics(pred):
+ pred_logits = pred.predictions
+ pred_ids = np.argmax(pred_logits, axis=-1)
+
+ pred.label_ids[pred.label_ids == -100] = tokenizer.pad_token_id
+
+ pred_str = tokenizer.batch_decode(pred_ids)
+ # we do not want to group tokens when computing the metrics
+ label_str = tokenizer.batch_decode(pred.label_ids, group_tokens=False)
+
+ metrics = {k: v.compute(predictions=pred_str, references=label_str) for k, v in eval_metrics.items()}
+
+ return metrics
+
+ # Now save everything to be able to create a single processor later
+ # make sure all processes wait until data is saved
+ with training_args.main_process_first():
+ # only the main process saves them
+ if is_main_process(training_args.local_rank):
+ # save feature extractor, tokenizer and config
+ feature_extractor.save_pretrained(training_args.output_dir)
+ tokenizer.save_pretrained(training_args.output_dir)
+ config.save_pretrained(training_args.output_dir)
+
+ try:
+ processor = AutoProcessor.from_pretrained(training_args.output_dir)
+ except (OSError, KeyError):
+ warnings.warn(
+ "Loading a processor from a feature extractor config that does not"
+ " include a `processor_class` attribute is deprecated and will be removed in v5. Please add the following "
+ " attribute to your `preprocessor_config.json` file to suppress this warning: "
+ " `'processor_class': 'Wav2Vec2Processor'`",
+ FutureWarning,
+ )
+ processor = Wav2Vec2Processor.from_pretrained(training_args.output_dir)
+
+ # Instantiate custom data collator
+ data_collator = DataCollatorCTCWithPadding(processor=processor)
+
+ # Initialize Trainer
+ trainer = Trainer(
+ model=model,
+ data_collator=data_collator,
+ args=training_args,
+ compute_metrics=compute_metrics,
+ train_dataset=vectorized_datasets["train"] if training_args.do_train else None,
+ eval_dataset=vectorized_datasets["eval"] if training_args.do_eval else None,
+ processing_class=processor,
+ )
+
+ # 8. Finally, we can start training
+
+ # Training
+ if training_args.do_train:
+ # use last checkpoint if exist
+ if last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ elif os.path.isdir(model_args.model_name_or_path):
+ checkpoint = model_args.model_name_or_path
+ else:
+ checkpoint = None
+
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model()
+
+ metrics = train_result.metrics
+ max_train_samples = (
+ data_args.max_train_samples
+ if data_args.max_train_samples is not None
+ else len(vectorized_datasets["train"])
+ )
+ metrics["train_samples"] = min(max_train_samples, len(vectorized_datasets["train"]))
+
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ results = {}
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+ metrics = trainer.evaluate()
+ max_eval_samples = (
+ data_args.max_eval_samples if data_args.max_eval_samples is not None else len(vectorized_datasets["eval"])
+ )
+ metrics["eval_samples"] = min(max_eval_samples, len(vectorized_datasets["eval"]))
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ # Write model card and (optionally) push to hub
+ config_name = data_args.dataset_config_name if data_args.dataset_config_name is not None else "na"
+ kwargs = {
+ "finetuned_from": model_args.model_name_or_path,
+ "tasks": "automatic-speech-recognition",
+ "tags": ["automatic-speech-recognition", data_args.dataset_name, "mms"],
+ "dataset_args": (
+ f"Config: {config_name}, Training split: {data_args.train_split_name}, Eval split:"
+ f" {data_args.eval_split_name}"
+ ),
+ "dataset": f"{data_args.dataset_name.upper()} - {config_name.upper()}",
+ }
+ if "common_voice" in data_args.dataset_name:
+ kwargs["language"] = config_name
+
+ # make sure that adapter weights are saved seperately
+ adapter_file = WAV2VEC2_ADAPTER_SAFE_FILE.format(data_args.target_language)
+ adapter_file = os.path.join(training_args.output_dir, adapter_file)
+ logger.info(f"Saving adapter weights under {adapter_file}...")
+ safe_save_file(model._get_adapters(), adapter_file, metadata={"format": "pt"})
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+ return results
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-recognition/run_speech_recognition_seq2seq.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-recognition/run_speech_recognition_seq2seq.py
new file mode 100644
index 0000000000000000000000000000000000000000..6d3950802c83efa3078f14069195e7fd3a47ff18
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/speech-recognition/run_speech_recognition_seq2seq.py
@@ -0,0 +1,634 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for sequence to sequence speech recognition.
+"""
+# You can also adapt this script on your own sequence to sequence speech
+# recognition task. Pointers for this are left as comments.
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from typing import Any, Dict, List, Optional, Union
+
+import datasets
+import evaluate
+import torch
+from datasets import DatasetDict, load_dataset
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoFeatureExtractor,
+ AutoModelForSpeechSeq2Seq,
+ AutoProcessor,
+ AutoTokenizer,
+ HfArgumentParser,
+ Seq2SeqTrainer,
+ Seq2SeqTrainingArguments,
+ set_seed,
+)
+from transformers.trainer_utils import get_last_checkpoint, is_main_process
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.18.0", "To fix: pip install -r examples/pytorch/speech-recognition/requirements.txt")
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ feature_extractor_name: Optional[str] = field(
+ default=None, metadata={"help": "feature extractor name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where to store the pretrained models downloaded from huggingface.co"},
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ freeze_feature_encoder: bool = field(
+ default=True, metadata={"help": "Whether to freeze the feature encoder layers of the model."}
+ )
+ freeze_encoder: bool = field(
+ default=False, metadata={"help": "Whether to freeze the entire encoder of the seq2seq model."}
+ )
+ forced_decoder_ids: List[List[int]] = field(
+ default=None,
+ metadata={"help": "Deprecated. Please use the `language` and `task` arguments instead."},
+ )
+ suppress_tokens: List[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Deprecated. The use of `suppress_tokens` should not be required for the majority of fine-tuning examples."
+ "Should you need to use `suppress_tokens`, please manually update them in the fine-tuning script directly."
+ )
+ },
+ )
+ apply_spec_augment: bool = field(
+ default=False,
+ metadata={
+ "help": "Whether to apply *SpecAugment* data augmentation to the input features. This is currently only relevant for Wav2Vec2, HuBERT, WavLM and Whisper models."
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: str = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ audio_column_name: str = field(
+ default="audio",
+ metadata={"help": "The name of the dataset column containing the audio data. Defaults to 'audio'"},
+ )
+ text_column_name: str = field(
+ default="text",
+ metadata={"help": "The name of the dataset column containing the text data. Defaults to 'text'"},
+ )
+ max_duration_in_seconds: float = field(
+ default=20.0,
+ metadata={
+ "help": (
+ "Truncate audio files that are longer than `max_duration_in_seconds` seconds to"
+ " 'max_duration_in_seconds`"
+ )
+ },
+ )
+ min_duration_in_seconds: float = field(
+ default=0.0, metadata={"help": "Filter audio files that are shorter than `min_duration_in_seconds` seconds"}
+ )
+ preprocessing_only: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to only do data preprocessing and skip training. This is especially useful when data"
+ " preprocessing errors out in distributed training due to timeout. In this case, one should run the"
+ " preprocessing in a non-distributed setup with `preprocessing_only=True` so that the cached datasets"
+ " can consequently be loaded in distributed training"
+ )
+ },
+ )
+ train_split_name: str = field(
+ default="train",
+ metadata={
+ "help": "The name of the training data set split to use (via the datasets library). Defaults to 'train'"
+ },
+ )
+ eval_split_name: str = field(
+ default="test",
+ metadata={
+ "help": "The name of the training data set split to use (via the datasets library). Defaults to 'train'"
+ },
+ )
+ do_lower_case: bool = field(
+ default=True,
+ metadata={"help": "Whether the target text should be lower cased."},
+ )
+ language: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "Language for multilingual fine-tuning. This argument should be set for multilingual fine-tuning "
+ "only. For English speech recognition, it should be set to `None`."
+ )
+ },
+ )
+ task: str = field(
+ default="transcribe",
+ metadata={"help": "Task, either `transcribe` for speech recognition or `translate` for speech translation."},
+ )
+
+
+@dataclass
+class DataCollatorSpeechSeq2SeqWithPadding:
+ """
+ Data collator that will dynamically pad the inputs received.
+ Args:
+ processor ([`WhisperProcessor`])
+ The processor used for processing the data.
+ decoder_start_token_id (`int`)
+ The begin-of-sentence of the decoder.
+ forward_attention_mask (`bool`)
+ Whether to return attention_mask.
+ """
+
+ processor: Any
+ decoder_start_token_id: int
+ forward_attention_mask: bool
+
+ def __call__(self, features: List[Dict[str, Union[List[int], torch.Tensor]]]) -> Dict[str, torch.Tensor]:
+ # split inputs and labels since they have to be of different lengths and need
+ # different padding methods
+ model_input_name = self.processor.model_input_names[0]
+ input_features = [{model_input_name: feature[model_input_name]} for feature in features]
+ label_features = [{"input_ids": feature["labels"]} for feature in features]
+
+ batch = self.processor.feature_extractor.pad(input_features, return_tensors="pt")
+
+ if self.forward_attention_mask:
+ batch["attention_mask"] = torch.LongTensor([feature["attention_mask"] for feature in features])
+
+ labels_batch = self.processor.tokenizer.pad(label_features, return_tensors="pt")
+
+ # replace padding with -100 to ignore loss correctly
+ labels = labels_batch["input_ids"].masked_fill(labels_batch.attention_mask.ne(1), -100)
+
+ # if bos token is appended in previous tokenization step,
+ # cut bos token here as it's append later anyways
+ if (labels[:, 0] == self.decoder_start_token_id).all().cpu().item():
+ labels = labels[:, 1:]
+
+ batch["labels"] = labels
+
+ return batch
+
+
+def main():
+ # 1. Parse input arguments
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, Seq2SeqTrainingArguments))
+
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_speech_recognition_seq2seq", model_args, data_args)
+
+ # 2. Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ datasets.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ logger.setLevel(logging.INFO if is_main_process(training_args.local_rank) else logging.WARN)
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ if is_main_process(training_args.local_rank):
+ transformers.utils.logging.set_verbosity_info()
+ logger.info("Training/evaluation parameters %s", training_args)
+
+ # 3. Detecting last checkpoint and eventually continue from last checkpoint
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # 4. Load dataset
+ raw_datasets = DatasetDict()
+
+ if training_args.do_train:
+ raw_datasets["train"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=data_args.train_split_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ if training_args.do_eval:
+ raw_datasets["eval"] = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ split=data_args.eval_split_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ if data_args.audio_column_name not in next(iter(raw_datasets.values())).column_names:
+ raise ValueError(
+ f"--audio_column_name '{data_args.audio_column_name}' not found in dataset '{data_args.dataset_name}'. "
+ "Make sure to set `--audio_column_name` to the correct audio column - one of "
+ f"{', '.join(next(iter(raw_datasets.values())).column_names)}."
+ )
+
+ if data_args.text_column_name not in next(iter(raw_datasets.values())).column_names:
+ raise ValueError(
+ f"--text_column_name {data_args.text_column_name} not found in dataset '{data_args.dataset_name}'. "
+ "Make sure to set `--text_column_name` to the correct text column - one of "
+ f"{', '.join(next(iter(raw_datasets.values())).column_names)}."
+ )
+
+ # 5. Load pretrained model, tokenizer, and feature extractor
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ # SpecAugment for whisper models
+ if getattr(config, "model_type", None) == "whisper":
+ config.update({"apply_spec_augment": model_args.apply_spec_augment})
+
+ feature_extractor = AutoFeatureExtractor.from_pretrained(
+ model_args.feature_extractor_name if model_args.feature_extractor_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ model = AutoModelForSpeechSeq2Seq.from_pretrained(
+ model_args.model_name_or_path,
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ if model.config.decoder_start_token_id is None:
+ raise ValueError("Make sure that `config.decoder_start_token_id` is correctly defined")
+
+ if model_args.freeze_feature_encoder:
+ model.freeze_feature_encoder()
+
+ if model_args.freeze_encoder:
+ model.freeze_encoder()
+ model.model.encoder.gradient_checkpointing = False
+
+ if hasattr(model.generation_config, "is_multilingual") and model.generation_config.is_multilingual:
+ # We only need to set the language and task ids in a multilingual setting
+ tokenizer.set_prefix_tokens(language=data_args.language, task=data_args.task)
+ model.generation_config.language = data_args.language
+ model.generation_config.task = data_args.task
+ elif data_args.language is not None:
+ raise ValueError(
+ "Setting language token for an English-only checkpoint is not permitted. The language argument should "
+ "only be set for multilingual checkpoints."
+ )
+
+ # TODO (Sanchit): deprecate these arguments in v4.41
+ if model_args.forced_decoder_ids is not None:
+ logger.warning(
+ "The use of `forced_decoder_ids` is deprecated and will be removed in v4.41."
+ "Please use the `language` and `task` arguments instead"
+ )
+ model.generation_config.forced_decoder_ids = model_args.forced_decoder_ids
+ else:
+ model.generation_config.forced_decoder_ids = None
+ model.config.forced_decoder_ids = None
+
+ if model_args.suppress_tokens is not None:
+ logger.warning(
+ "The use of `suppress_tokens` is deprecated and will be removed in v4.41."
+ "Should you need `suppress_tokens`, please manually set them in the fine-tuning script."
+ )
+ model.generation_config.suppress_tokens = model_args.suppress_tokens
+
+ # 6. Resample speech dataset if necessary
+ dataset_sampling_rate = next(iter(raw_datasets.values())).features[data_args.audio_column_name].sampling_rate
+ if dataset_sampling_rate != feature_extractor.sampling_rate:
+ raw_datasets = raw_datasets.cast_column(
+ data_args.audio_column_name, datasets.features.Audio(sampling_rate=feature_extractor.sampling_rate)
+ )
+
+ # 7. Preprocessing the datasets.
+ # We need to read the audio files as arrays and tokenize the targets.
+ max_input_length = data_args.max_duration_in_seconds * feature_extractor.sampling_rate
+ min_input_length = data_args.min_duration_in_seconds * feature_extractor.sampling_rate
+ audio_column_name = data_args.audio_column_name
+ num_workers = data_args.preprocessing_num_workers
+ text_column_name = data_args.text_column_name
+ model_input_name = feature_extractor.model_input_names[0]
+ do_lower_case = data_args.do_lower_case
+ # if SpecAugment is used for whisper models, return attention_mask to guide the mask along time axis
+ forward_attention_mask = (
+ getattr(config, "model_type", None) == "whisper"
+ and getattr(config, "apply_spec_augment", False)
+ and getattr(config, "mask_time_prob", 0) > 0
+ )
+
+ if data_args.max_train_samples is not None:
+ raw_datasets["train"] = raw_datasets["train"].select(range(data_args.max_train_samples))
+
+ if data_args.max_eval_samples is not None:
+ raw_datasets["eval"] = raw_datasets["eval"].select(range(data_args.max_eval_samples))
+
+ def prepare_dataset(batch):
+ # process audio
+ sample = batch[audio_column_name]
+ inputs = feature_extractor(
+ sample["array"], sampling_rate=sample["sampling_rate"], return_attention_mask=forward_attention_mask
+ )
+ # process audio length
+ batch[model_input_name] = inputs.get(model_input_name)[0]
+ batch["input_length"] = len(sample["array"])
+ if forward_attention_mask:
+ batch["attention_mask"] = inputs.get("attention_mask")[0]
+
+ # process targets
+ input_str = batch[text_column_name].lower() if do_lower_case else batch[text_column_name]
+ batch["labels"] = tokenizer(input_str).input_ids
+ return batch
+
+ with training_args.main_process_first(desc="dataset map pre-processing"):
+ vectorized_datasets = raw_datasets.map(
+ prepare_dataset,
+ remove_columns=next(iter(raw_datasets.values())).column_names,
+ num_proc=data_args.preprocessing_num_workers,
+ desc="preprocess train dataset",
+ )
+
+ # filter data that is shorter than min_input_length or longer than
+ # max_input_length
+ def is_audio_in_length_range(length):
+ return length > min_input_length and length < max_input_length
+
+ vectorized_datasets = vectorized_datasets.filter(
+ is_audio_in_length_range,
+ num_proc=num_workers,
+ input_columns=["input_length"],
+ )
+
+ # for large datasets it is advised to run the preprocessing on a
+ # single machine first with `args.preprocessing_only` since there will mostly likely
+ # be a timeout when running the script in distributed mode.
+ # In a second step `args.preprocessing_only` can then be set to `False` to load the
+ # cached dataset
+ if data_args.preprocessing_only:
+ cache = {k: v.cache_files for k, v in vectorized_datasets.items()}
+ logger.info(f"Data preprocessing finished. Files cached at {cache}.")
+ return
+
+ # 8. Load Metric
+ metric = evaluate.load("wer", cache_dir=model_args.cache_dir)
+
+ def compute_metrics(pred):
+ pred_ids = pred.predictions
+
+ pred.label_ids[pred.label_ids == -100] = tokenizer.pad_token_id
+
+ pred_str = tokenizer.batch_decode(pred_ids, skip_special_tokens=True)
+ # we do not want to group tokens when computing the metrics
+ label_str = tokenizer.batch_decode(pred.label_ids, skip_special_tokens=True)
+
+ wer = metric.compute(predictions=pred_str, references=label_str)
+
+ return {"wer": wer}
+
+ # 9. Create a single speech processor
+ # make sure all processes wait until data is saved
+ with training_args.main_process_first():
+ # only the main process saves them
+ if is_main_process(training_args.local_rank):
+ # save feature extractor, tokenizer and config
+ feature_extractor.save_pretrained(training_args.output_dir)
+ tokenizer.save_pretrained(training_args.output_dir)
+ config.save_pretrained(training_args.output_dir)
+
+ processor = AutoProcessor.from_pretrained(training_args.output_dir)
+
+ # 10. Define data collator
+ data_collator = DataCollatorSpeechSeq2SeqWithPadding(
+ processor=processor,
+ decoder_start_token_id=model.config.decoder_start_token_id,
+ forward_attention_mask=forward_attention_mask,
+ )
+
+ # 11. Initialize Trainer
+ trainer = Seq2SeqTrainer(
+ model=model,
+ args=training_args,
+ train_dataset=vectorized_datasets["train"] if training_args.do_train else None,
+ eval_dataset=vectorized_datasets["eval"] if training_args.do_eval else None,
+ processing_class=feature_extractor,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics if training_args.predict_with_generate else None,
+ )
+
+ # 12. Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model() # Saves the feature extractor too for easy upload
+
+ metrics = train_result.metrics
+ max_train_samples = (
+ data_args.max_train_samples
+ if data_args.max_train_samples is not None
+ else len(vectorized_datasets["train"])
+ )
+ metrics["train_samples"] = min(max_train_samples, len(vectorized_datasets["train"]))
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # 13. Evaluation
+ results = {}
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+ metrics = trainer.evaluate(
+ metric_key_prefix="eval",
+ max_length=training_args.generation_max_length,
+ num_beams=training_args.generation_num_beams,
+ )
+ max_eval_samples = (
+ data_args.max_eval_samples if data_args.max_eval_samples is not None else len(vectorized_datasets["eval"])
+ )
+ metrics["eval_samples"] = min(max_eval_samples, len(vectorized_datasets["eval"]))
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ # 14. Write Training Stats
+ kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "automatic-speech-recognition"}
+ if data_args.dataset_name is not None:
+ kwargs["dataset_tags"] = data_args.dataset_name
+ if data_args.dataset_config_name is not None:
+ kwargs["dataset_args"] = data_args.dataset_config_name
+ kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
+ else:
+ kwargs["dataset"] = data_args.dataset_name
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+ return results
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/summarization/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/summarization/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..93c0bbccef6c06239a9bf3cb0d2462c3a7d9b122
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/summarization/README.md
@@ -0,0 +1,196 @@
+
+
+## Summarization
+
+This directory contains examples for finetuning and evaluating transformers on summarization tasks.
+Please tag @patil-suraj with any issues/unexpected behaviors, or send a PR!
+For deprecated `bertabs` instructions, see [`bertabs/README.md`](https://github.com/huggingface/transformers/blob/main/examples/research_projects/bertabs/README.md).
+For the old `finetune_trainer.py` and related utils, see [`examples/legacy/seq2seq`](https://github.com/huggingface/transformers/blob/main/examples/legacy/seq2seq).
+
+### Supported Architectures
+
+- `BartForConditionalGeneration`
+- `FSMTForConditionalGeneration` (translation only)
+- `MBartForConditionalGeneration`
+- `MarianMTModel`
+- `PegasusForConditionalGeneration`
+- `T5ForConditionalGeneration`
+- `MT5ForConditionalGeneration`
+
+`run_summarization.py` is a lightweight example of how to download and preprocess a dataset from the [🤗 Datasets](https://github.com/huggingface/datasets) library or use your own files (jsonlines or csv), then fine-tune one of the architectures above on it.
+
+For custom datasets in `jsonlines` format please see: https://huggingface.co/docs/datasets/loading_datasets#json-files
+and you also will find examples of these below.
+
+## With Trainer
+
+Here is an example on a summarization task:
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+Only T5 models `google-t5/t5-small`, `google-t5/t5-base`, `google-t5/t5-large`, `google-t5/t5-3b` and `google-t5/t5-11b` must use an additional argument: `--source_prefix "summarize: "`.
+
+We used CNN/DailyMail dataset in this example as `google-t5/t5-small` was trained on it and one can get good scores even when pre-training with a very small sample.
+
+Extreme Summarization (XSum) Dataset is another commonly used dataset for the task of summarization. To use it replace `--dataset_name cnn_dailymail --dataset_config "3.0.0"` with `--dataset_name xsum`.
+
+And here is how you would use it on your own files, after adjusting the values for the arguments
+`--train_file`, `--validation_file`, `--text_column` and `--summary_column` to match your setup:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --train_file path_to_csv_or_jsonlines_file \
+ --validation_file path_to_csv_or_jsonlines_file \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --overwrite_output_dir \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --predict_with_generate
+```
+
+The task of summarization supports custom CSV and JSONLINES formats.
+
+#### Custom CSV Files
+
+If it's a csv file the training and validation files should have a column for the inputs texts and a column for the summaries.
+
+If the csv file has just two columns as in the following example:
+
+```csv
+text,summary
+"I'm sitting here in a boring room. It's just another rainy Sunday afternoon. I'm wasting my time I got nothing to do. I'm hanging around I'm waiting for you. But nothing ever happens. And I wonder","I'm sitting in a room where I'm waiting for something to happen"
+"I see trees so green, red roses too. I see them bloom for me and you. And I think to myself what a wonderful world. I see skies so blue and clouds so white. The bright blessed day, the dark sacred night. And I think to myself what a wonderful world.","I'm a gardener and I'm a big fan of flowers."
+"Christmas time is here. Happiness and cheer. Fun for all that children call. Their favorite time of the year. Snowflakes in the air. Carols everywhere. Olden times and ancient rhymes. Of love and dreams to share","It's that time of year again."
+```
+
+The first column is assumed to be for `text` and the second is for summary.
+
+If the csv file has multiple columns, you can then specify the names of the columns to use:
+
+```bash
+ --text_column text_column_name \
+ --summary_column summary_column_name \
+```
+
+For example if the columns were:
+
+```csv
+id,date,text,summary
+```
+
+and you wanted to select only `text` and `summary`, then you'd pass these additional arguments:
+
+```bash
+ --text_column text \
+ --summary_column summary \
+```
+
+#### Custom JSONLINES Files
+
+The second supported format is jsonlines. Here is an example of a jsonlines custom data file.
+
+
+```json
+{"text": "I'm sitting here in a boring room. It's just another rainy Sunday afternoon. I'm wasting my time I got nothing to do. I'm hanging around I'm waiting for you. But nothing ever happens. And I wonder", "summary": "I'm sitting in a room where I'm waiting for something to happen"}
+{"text": "I see trees so green, red roses too. I see them bloom for me and you. And I think to myself what a wonderful world. I see skies so blue and clouds so white. The bright blessed day, the dark sacred night. And I think to myself what a wonderful world.", "summary": "I'm a gardener and I'm a big fan of flowers."}
+{"text": "Christmas time is here. Happiness and cheer. Fun for all that children call. Their favorite time of the year. Snowflakes in the air. Carols everywhere. Olden times and ancient rhymes. Of love and dreams to share", "summary": "It's that time of year again."}
+```
+
+Same as with the CSV files, by default the first value will be used as the text record and the second as the summary record. Therefore you can use any key names for the entries, in this example `text` and `summary` were used.
+
+And as with the CSV files, you can specify which values to select from the file, by explicitly specifying the corresponding key names. In our example this again would be:
+
+```bash
+ --text_column text \
+ --summary_column summary \
+```
+
+## With Accelerate
+
+Based on the script [`run_summarization_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/summarization/run_summarization_no_trainer.py).
+
+Like `run_summarization.py`, this script allows you to fine-tune any of the models supported on a
+summarization task, the main difference is that this
+script exposes the bare training loop, to allow you to quickly experiment and add any customization you would like.
+
+It offers less options than the script with `Trainer` (for instance you can easily change the options for the optimizer
+or the dataloaders directly in the script) but still run in a distributed setup, on TPU and supports mixed precision by
+the mean of the [🤗 `Accelerate`](https://github.com/huggingface/accelerate) library. You can use the script normally
+after installing it:
+
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+then
+
+```bash
+python run_summarization_no_trainer.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir ~/tmp/tst-summarization
+```
+
+You can then use your usual launchers to run in it in a distributed environment, but the easiest way is to run
+
+```bash
+accelerate config
+```
+
+and reply to the questions asked. Then
+
+```bash
+accelerate test
+```
+
+that will check everything is ready for training. Finally, you can launch training with
+
+```bash
+accelerate launch run_summarization_no_trainer.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir ~/tmp/tst-summarization
+```
+
+This command is the same and will work for:
+
+- a CPU-only setup
+- a setup with one GPU
+- a distributed training with several GPUs (single or multi node)
+- a training on TPUs
+
+Note that this library is in alpha release so your feedback is more than welcome if you encounter any problem using it.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/summarization/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/summarization/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..efc067478603d253fa6ec2fd309328307c562c79
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/summarization/requirements.txt
@@ -0,0 +1,9 @@
+accelerate >= 0.12.0
+datasets >= 1.8.0
+sentencepiece != 0.1.92
+protobuf
+rouge-score
+nltk
+py7zr
+torch >= 1.3
+evaluate
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/summarization/run_summarization.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/summarization/run_summarization.py
new file mode 100644
index 0000000000000000000000000000000000000000..93036a7e03ac06a207a3939629f934301af1cabf
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/summarization/run_summarization.py
@@ -0,0 +1,773 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for sequence to sequence.
+"""
+# You can also adapt this script on your own sequence to sequence task. Pointers for this are left as comments.
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from typing import Optional
+
+import datasets
+import evaluate
+import nltk # Here to have a nice missing dependency error message early on
+import numpy as np
+from datasets import load_dataset
+from filelock import FileLock
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForSeq2SeqLM,
+ AutoTokenizer,
+ DataCollatorForSeq2Seq,
+ HfArgumentParser,
+ MBart50Tokenizer,
+ MBart50TokenizerFast,
+ MBartTokenizer,
+ MBartTokenizerFast,
+ Seq2SeqTrainer,
+ Seq2SeqTrainingArguments,
+ set_seed,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, is_offline_mode, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/summarization/requirements.txt")
+
+logger = logging.getLogger(__name__)
+
+try:
+ nltk.data.find("tokenizers/punkt")
+except (LookupError, OSError):
+ if is_offline_mode():
+ raise LookupError(
+ "Offline mode: run this script without TRANSFORMERS_OFFLINE first to download nltk data files"
+ )
+ with FileLock(".lock") as lock:
+ nltk.download("punkt", quiet=True)
+
+# A list of all multilingual tokenizer which require lang attribute.
+MULTILINGUAL_TOKENIZERS = [MBartTokenizer, MBartTokenizerFast, MBart50Tokenizer, MBart50TokenizerFast]
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where to store the pretrained models downloaded from huggingface.co"},
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ resize_position_embeddings: Optional[bool] = field(
+ default=None,
+ metadata={
+ "help": (
+ "Whether to automatically resize the position embeddings if `max_source_length` exceeds "
+ "the model's position embeddings."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ lang: Optional[str] = field(default=None, metadata={"help": "Language id for summarization."})
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ text_column: Optional[str] = field(
+ default=None,
+ metadata={"help": "The name of the column in the datasets containing the full texts (for summarization)."},
+ )
+ summary_column: Optional[str] = field(
+ default=None,
+ metadata={"help": "The name of the column in the datasets containing the summaries (for summarization)."},
+ )
+ train_file: Optional[str] = field(
+ default=None, metadata={"help": "The input training data file (a jsonlines or csv file)."}
+ )
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "An optional input evaluation data file to evaluate the metrics (rouge) on (a jsonlines or csv file)."
+ )
+ },
+ )
+ test_file: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": "An optional input test data file to evaluate the metrics (rouge) on (a jsonlines or csv file)."
+ },
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ max_source_length: Optional[int] = field(
+ default=1024,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ max_target_length: Optional[int] = field(
+ default=128,
+ metadata={
+ "help": (
+ "The maximum total sequence length for target text after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ val_max_target_length: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The maximum total sequence length for validation target text after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded. Will default to `max_target_length`. "
+ "This argument is also used to override the ``max_length`` param of ``model.generate``, which is used "
+ "during ``evaluate`` and ``predict``."
+ )
+ },
+ )
+ pad_to_max_length: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to pad all samples to model maximum sentence length. "
+ "If False, will pad the samples dynamically when batching to the maximum length in the batch. More "
+ "efficient on GPU but very bad for TPU."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_predict_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of prediction examples to this "
+ "value if set."
+ )
+ },
+ )
+ num_beams: Optional[int] = field(
+ default=1,
+ metadata={
+ "help": (
+ "Number of beams to use for evaluation. This argument will be passed to ``model.generate``, "
+ "which is used during ``evaluate`` and ``predict``."
+ )
+ },
+ )
+ ignore_pad_token_for_loss: bool = field(
+ default=True,
+ metadata={
+ "help": "Whether to ignore the tokens corresponding to padded labels in the loss computation or not."
+ },
+ )
+ source_prefix: Optional[str] = field(
+ default=None, metadata={"help": "A prefix to add before every source text (useful for T5 models)."}
+ )
+
+ forced_bos_token: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to force as the first generated token after the decoder_start_token_id. "
+ "Useful for multilingual models like mBART where the first generated token"
+ "needs to be the target language token (Usually it is the target language token)"
+ )
+ },
+ )
+
+ def __post_init__(self):
+ if (
+ self.dataset_name is None
+ and self.train_file is None
+ and self.validation_file is None
+ and self.test_file is None
+ ):
+ raise ValueError("Need either a dataset name or a training, validation, or test file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+ if self.test_file is not None:
+ extension = self.test_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`test_file` should be a csv or a json file."
+ if self.val_max_target_length is None:
+ self.val_max_target_length = self.max_target_length
+
+
+summarization_name_mapping = {
+ "amazon_reviews_multi": ("review_body", "review_title"),
+ "big_patent": ("description", "abstract"),
+ "cnn_dailymail": ("article", "highlights"),
+ "orange_sum": ("text", "summary"),
+ "pn_summary": ("article", "summary"),
+ "psc": ("extract_text", "summary_text"),
+ "samsum": ("dialogue", "summary"),
+ "thaisum": ("body", "summary"),
+ "xglue": ("news_body", "news_title"),
+ "xsum": ("document", "summary"),
+ "wiki_summary": ("article", "highlights"),
+ "multi_news": ("document", "summary"),
+}
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, Seq2SeqTrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_summarization", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ datasets.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ if data_args.source_prefix is None and model_args.model_name_or_path in [
+ "google-t5/t5-small",
+ "google-t5/t5-base",
+ "google-t5/t5-large",
+ "google-t5/t5-3b",
+ "google-t5/t5-11b",
+ ]:
+ logger.warning(
+ "You're running a t5 model but didn't provide a source prefix, which is the expected, e.g. with "
+ "`--source_prefix 'summarize: ' `"
+ )
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Get the datasets: you can either provide your own CSV/JSON training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files this script will use the first column for the full texts and the second column for the
+ # summaries (unless you specify column names for this with the `text_column` and `summary_column` arguments).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ if data_args.test_file is not None:
+ data_files["test"] = data_args.test_file
+ extension = data_args.test_file.split(".")[-1]
+ raw_datasets = load_dataset(
+ extension,
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ model = AutoModelForSeq2SeqLM.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
+ # on a small vocab and want a smaller embedding size, remove this test.
+ embedding_size = model.get_input_embeddings().weight.shape[0]
+ if len(tokenizer) > embedding_size:
+ model.resize_token_embeddings(len(tokenizer))
+
+ if model.config.decoder_start_token_id is None and isinstance(tokenizer, (MBartTokenizer, MBartTokenizerFast)):
+ if isinstance(tokenizer, MBartTokenizer):
+ model.config.decoder_start_token_id = tokenizer.lang_code_to_id[data_args.lang]
+ else:
+ model.config.decoder_start_token_id = tokenizer.convert_tokens_to_ids(data_args.lang)
+
+ if model.config.decoder_start_token_id is None:
+ raise ValueError("Make sure that `config.decoder_start_token_id` is correctly defined")
+
+ if (
+ hasattr(model.config, "max_position_embeddings")
+ and model.config.max_position_embeddings < data_args.max_source_length
+ ):
+ if model_args.resize_position_embeddings is None:
+ logger.warning(
+ "Increasing the model's number of position embedding vectors from"
+ f" {model.config.max_position_embeddings} to {data_args.max_source_length}."
+ )
+ model.resize_position_embeddings(data_args.max_source_length)
+ elif model_args.resize_position_embeddings:
+ model.resize_position_embeddings(data_args.max_source_length)
+ else:
+ raise ValueError(
+ f"`--max_source_length` is set to {data_args.max_source_length}, but the model only has"
+ f" {model.config.max_position_embeddings} position encodings. Consider either reducing"
+ f" `--max_source_length` to {model.config.max_position_embeddings} or to automatically resize the"
+ " model's position encodings by passing `--resize_position_embeddings`."
+ )
+
+ prefix = data_args.source_prefix if data_args.source_prefix is not None else ""
+
+ # Preprocessing the datasets.
+ # We need to tokenize inputs and targets.
+ if training_args.do_train:
+ if "train" not in raw_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ column_names = raw_datasets["train"].column_names
+ elif training_args.do_eval:
+ if "validation" not in raw_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ column_names = raw_datasets["validation"].column_names
+ elif training_args.do_predict:
+ if "test" not in raw_datasets:
+ raise ValueError("--do_predict requires a test dataset")
+ column_names = raw_datasets["test"].column_names
+ else:
+ logger.info("There is nothing to do. Please pass `do_train`, `do_eval` and/or `do_predict`.")
+ return
+
+ if isinstance(tokenizer, tuple(MULTILINGUAL_TOKENIZERS)):
+ assert (
+ data_args.lang is not None
+ ), f"{tokenizer.__class__.__name__} is a multilingual tokenizer which requires --lang argument"
+
+ tokenizer.src_lang = data_args.lang
+ tokenizer.tgt_lang = data_args.lang
+
+ # For multilingual translation models like mBART-50 and M2M100 we need to force the target language token
+ # as the first generated token. We ask the user to explicitly provide this as --forced_bos_token argument.
+ forced_bos_token_id = (
+ tokenizer.lang_code_to_id[data_args.forced_bos_token] if data_args.forced_bos_token is not None else None
+ )
+ model.config.forced_bos_token_id = forced_bos_token_id
+
+ # Get the column names for input/target.
+ dataset_columns = summarization_name_mapping.get(data_args.dataset_name, None)
+ if data_args.text_column is None:
+ text_column = dataset_columns[0] if dataset_columns is not None else column_names[0]
+ else:
+ text_column = data_args.text_column
+ if text_column not in column_names:
+ raise ValueError(
+ f"--text_column' value '{data_args.text_column}' needs to be one of: {', '.join(column_names)}"
+ )
+ if data_args.summary_column is None:
+ summary_column = dataset_columns[1] if dataset_columns is not None else column_names[1]
+ else:
+ summary_column = data_args.summary_column
+ if summary_column not in column_names:
+ raise ValueError(
+ f"--summary_column' value '{data_args.summary_column}' needs to be one of: {', '.join(column_names)}"
+ )
+
+ # Temporarily set max_target_length for training.
+ max_target_length = data_args.max_target_length
+ padding = "max_length" if data_args.pad_to_max_length else False
+
+ if training_args.label_smoothing_factor > 0 and not hasattr(model, "prepare_decoder_input_ids_from_labels"):
+ logger.warning(
+ "label_smoothing is enabled but the `prepare_decoder_input_ids_from_labels` method is not defined for "
+ f"`{model.__class__.__name__}`. This will lead to loss being calculated twice and will take up more memory"
+ )
+
+ def preprocess_function(examples):
+ # remove pairs where at least one record is None
+
+ inputs, targets = [], []
+ for i in range(len(examples[text_column])):
+ if examples[text_column][i] and examples[summary_column][i]:
+ inputs.append(examples[text_column][i])
+ targets.append(examples[summary_column][i])
+
+ inputs = [prefix + inp for inp in inputs]
+ model_inputs = tokenizer(inputs, max_length=data_args.max_source_length, padding=padding, truncation=True)
+
+ # Tokenize targets with the `text_target` keyword argument
+ labels = tokenizer(text_target=targets, max_length=max_target_length, padding=padding, truncation=True)
+
+ # If we are padding here, replace all tokenizer.pad_token_id in the labels by -100 when we want to ignore
+ # padding in the loss.
+ if padding == "max_length" and data_args.ignore_pad_token_for_loss:
+ labels["input_ids"] = [
+ [(l if l != tokenizer.pad_token_id else -100) for l in label] for label in labels["input_ids"]
+ ]
+
+ model_inputs["labels"] = labels["input_ids"]
+ return model_inputs
+
+ if training_args.do_train:
+ train_dataset = raw_datasets["train"]
+ if data_args.max_train_samples is not None:
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+ with training_args.main_process_first(desc="train dataset map pre-processing"):
+ train_dataset = train_dataset.map(
+ preprocess_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on train dataset",
+ )
+
+ if training_args.do_eval:
+ max_target_length = data_args.val_max_target_length
+ eval_dataset = raw_datasets["validation"]
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+ with training_args.main_process_first(desc="validation dataset map pre-processing"):
+ eval_dataset = eval_dataset.map(
+ preprocess_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on validation dataset",
+ )
+
+ if training_args.do_predict:
+ max_target_length = data_args.val_max_target_length
+ predict_dataset = raw_datasets["test"]
+ if data_args.max_predict_samples is not None:
+ max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
+ predict_dataset = predict_dataset.select(range(max_predict_samples))
+ with training_args.main_process_first(desc="prediction dataset map pre-processing"):
+ predict_dataset = predict_dataset.map(
+ preprocess_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on prediction dataset",
+ )
+
+ # Data collator
+ label_pad_token_id = -100 if data_args.ignore_pad_token_for_loss else tokenizer.pad_token_id
+ data_collator = DataCollatorForSeq2Seq(
+ tokenizer,
+ model=model,
+ label_pad_token_id=label_pad_token_id,
+ pad_to_multiple_of=8 if training_args.fp16 else None,
+ )
+
+ # Metric
+ metric = evaluate.load("rouge", cache_dir=model_args.cache_dir)
+
+ def postprocess_text(preds, labels):
+ preds = [pred.strip() for pred in preds]
+ labels = [label.strip() for label in labels]
+
+ # rougeLSum expects newline after each sentence
+ preds = ["\n".join(nltk.sent_tokenize(pred)) for pred in preds]
+ labels = ["\n".join(nltk.sent_tokenize(label)) for label in labels]
+
+ return preds, labels
+
+ def compute_metrics(eval_preds):
+ preds, labels = eval_preds
+ if isinstance(preds, tuple):
+ preds = preds[0]
+ # Replace -100s used for padding as we can't decode them
+ preds = np.where(preds != -100, preds, tokenizer.pad_token_id)
+ decoded_preds = tokenizer.batch_decode(preds, skip_special_tokens=True)
+ labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
+ decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+ # Some simple post-processing
+ decoded_preds, decoded_labels = postprocess_text(decoded_preds, decoded_labels)
+
+ result = metric.compute(predictions=decoded_preds, references=decoded_labels, use_stemmer=True)
+ result = {k: round(v * 100, 4) for k, v in result.items()}
+ prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in preds]
+ result["gen_len"] = np.mean(prediction_lens)
+ return result
+
+ # Override the decoding parameters of Seq2SeqTrainer
+ training_args.generation_max_length = (
+ training_args.generation_max_length
+ if training_args.generation_max_length is not None
+ else data_args.val_max_target_length
+ )
+ training_args.generation_num_beams = (
+ data_args.num_beams if data_args.num_beams is not None else training_args.generation_num_beams
+ )
+
+ # Initialize our Trainer
+ trainer = Seq2SeqTrainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset if training_args.do_train else None,
+ eval_dataset=eval_dataset if training_args.do_eval else None,
+ processing_class=tokenizer,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics if training_args.predict_with_generate else None,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model() # Saves the tokenizer too for easy upload
+
+ metrics = train_result.metrics
+ max_train_samples = (
+ data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
+ )
+ metrics["train_samples"] = min(max_train_samples, len(train_dataset))
+
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ results = {}
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+ if isinstance(eval_dataset, dict):
+ metrics = {}
+ for eval_ds_name, eval_ds in eval_dataset.items():
+ dataset_metrics = trainer.evaluate(eval_dataset=eval_ds, metric_key_prefix=f"eval_{eval_ds_name}")
+ metrics.update(dataset_metrics)
+ else:
+ metrics = trainer.evaluate(metric_key_prefix="eval")
+ max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
+ metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ if training_args.do_predict:
+ logger.info("*** Predict ***")
+
+ predict_results = trainer.predict(predict_dataset, metric_key_prefix="predict")
+ metrics = predict_results.metrics
+ max_predict_samples = (
+ data_args.max_predict_samples if data_args.max_predict_samples is not None else len(predict_dataset)
+ )
+ metrics["predict_samples"] = min(max_predict_samples, len(predict_dataset))
+
+ trainer.log_metrics("predict", metrics)
+ trainer.save_metrics("predict", metrics)
+
+ if trainer.is_world_process_zero():
+ if training_args.predict_with_generate:
+ predictions = predict_results.predictions
+ predictions = np.where(predictions != -100, predictions, tokenizer.pad_token_id)
+ predictions = tokenizer.batch_decode(
+ predictions, skip_special_tokens=True, clean_up_tokenization_spaces=True
+ )
+ predictions = [pred.strip() for pred in predictions]
+ output_prediction_file = os.path.join(training_args.output_dir, "generated_predictions.txt")
+ with open(output_prediction_file, "w") as writer:
+ writer.write("\n".join(predictions))
+
+ kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "summarization"}
+ if data_args.dataset_name is not None:
+ kwargs["dataset_tags"] = data_args.dataset_name
+ if data_args.dataset_config_name is not None:
+ kwargs["dataset_args"] = data_args.dataset_config_name
+ kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
+ else:
+ kwargs["dataset"] = data_args.dataset_name
+
+ if data_args.lang is not None:
+ kwargs["language"] = data_args.lang
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+ return results
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/summarization/run_summarization_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/summarization/run_summarization_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..c2201840cacc18bf3d2aeb164b79d9dfb5d9202b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/summarization/run_summarization_no_trainer.py
@@ -0,0 +1,801 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright The HuggingFace Team and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning a 🤗 Transformers model on summarization.
+"""
+# You can also adapt this script on your own summarization task. Pointers for this are left as comments.
+
+import argparse
+import json
+import logging
+import math
+import os
+import random
+from pathlib import Path
+
+import datasets
+import evaluate
+import nltk
+import numpy as np
+import torch
+from accelerate import Accelerator
+from accelerate.logging import get_logger
+from accelerate.utils import set_seed
+from datasets import load_dataset
+from filelock import FileLock
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from tqdm.auto import tqdm
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ MODEL_MAPPING,
+ AutoConfig,
+ AutoModelForSeq2SeqLM,
+ AutoTokenizer,
+ DataCollatorForSeq2Seq,
+ SchedulerType,
+ get_scheduler,
+)
+from transformers.utils import check_min_version, is_offline_mode, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+logger = get_logger(__name__)
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/summarization/requirements.txt")
+
+# You should update this to your particular problem to have better documentation of `model_type`
+MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+try:
+ nltk.data.find("tokenizers/punkt")
+except (LookupError, OSError):
+ if is_offline_mode():
+ raise LookupError(
+ "Offline mode: run this script without TRANSFORMERS_OFFLINE first to download nltk data files"
+ )
+ with FileLock(".lock") as lock:
+ nltk.download("punkt", quiet=True)
+
+summarization_name_mapping = {
+ "amazon_reviews_multi": ("review_body", "review_title"),
+ "big_patent": ("description", "abstract"),
+ "cnn_dailymail": ("article", "highlights"),
+ "orange_sum": ("text", "summary"),
+ "pn_summary": ("article", "summary"),
+ "psc": ("extract_text", "summary_text"),
+ "samsum": ("dialogue", "summary"),
+ "thaisum": ("body", "summary"),
+ "xglue": ("news_body", "news_title"),
+ "xsum": ("document", "summary"),
+ "wiki_summary": ("article", "highlights"),
+}
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Finetune a transformers model on a summarization task")
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ default=None,
+ help="The name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--dataset_config_name",
+ type=str,
+ default=None,
+ help="The configuration name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
+ )
+ parser.add_argument(
+ "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
+ )
+ parser.add_argument(
+ "--ignore_pad_token_for_loss",
+ type=bool,
+ default=True,
+ help="Whether to ignore the tokens corresponding to padded labels in the loss computation or not.",
+ )
+ parser.add_argument(
+ "--max_source_length",
+ type=int,
+ default=1024,
+ help=(
+ "The maximum total input sequence length after "
+ "tokenization.Sequences longer than this will be truncated, sequences shorter will be padded."
+ ),
+ )
+ parser.add_argument(
+ "--source_prefix",
+ type=str,
+ default=None,
+ help="A prefix to add before every source text (useful for T5 models).",
+ )
+ parser.add_argument(
+ "--preprocessing_num_workers",
+ type=int,
+ default=None,
+ help="The number of processes to use for the preprocessing.",
+ )
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+ parser.add_argument(
+ "--max_target_length",
+ type=int,
+ default=128,
+ help=(
+ "The maximum total sequence length for target text after "
+ "tokenization. Sequences longer than this will be truncated, sequences shorter will be padded. "
+ "during ``evaluate`` and ``predict``."
+ ),
+ )
+ parser.add_argument(
+ "--val_max_target_length",
+ type=int,
+ default=None,
+ help=(
+ "The maximum total sequence length for validation "
+ "target text after tokenization.Sequences longer than this will be truncated, sequences shorter will be "
+ "padded. Will default to `max_target_length`.This argument is also used to override the ``max_length`` "
+ "param of ``model.generate``, which is used during ``evaluate`` and ``predict``."
+ ),
+ )
+ parser.add_argument(
+ "--num_beams",
+ type=int,
+ default=None,
+ help=(
+ "Number of beams to use for evaluation. This argument will be "
+ "passed to ``model.generate``, which is used during ``evaluate`` and ``predict``."
+ ),
+ )
+ parser.add_argument(
+ "--pad_to_max_length",
+ action="store_true",
+ help="If passed, pad all samples to `max_length`. Otherwise, dynamic padding is used.",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=False,
+ )
+ parser.add_argument(
+ "--config_name",
+ type=str,
+ default=None,
+ help="Pretrained config name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ type=str,
+ default=None,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--text_column",
+ type=str,
+ default=None,
+ help="The name of the column in the datasets containing the full texts (for summarization).",
+ )
+ parser.add_argument(
+ "--summary_column",
+ type=str,
+ default=None,
+ help="The name of the column in the datasets containing the summaries (for summarization).",
+ )
+ parser.add_argument(
+ "--use_slow_tokenizer",
+ action="store_true",
+ help="If passed, will use a slow tokenizer (not backed by the 🤗 Tokenizers library).",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument(
+ "--model_type",
+ type=str,
+ default=None,
+ help="Model type to use if training from scratch.",
+ choices=MODEL_TYPES,
+ )
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--trust_remote_code",
+ action="store_true",
+ help=(
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+ if args.dataset_name is None and args.train_file is None and args.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if args.train_file is not None:
+ extension = args.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if args.validation_file is not None:
+ extension = args.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+
+ if args.push_to_hub:
+ assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
+
+ return args
+
+
+def main():
+ args = parse_args()
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_summarization_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+ accelerator_log_kwargs = {}
+
+ if args.with_tracking:
+ accelerator_log_kwargs["log_with"] = args.report_to
+ accelerator_log_kwargs["project_dir"] = args.output_dir
+
+ accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
+ if args.source_prefix is None and args.model_name_or_path in [
+ "google-t5/t5-small",
+ "google-t5/t5-base",
+ "google-t5/t5-large",
+ "google-t5/t5-3b",
+ "google-t5/t5-11b",
+ ]:
+ logger.warning(
+ "You're running a t5 model but didn't provide a source prefix, which is the expected, e.g. with "
+ "`--source_prefix 'summarize: ' `"
+ )
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
+ )
+ else:
+ data_files = {}
+ if args.train_file is not None:
+ data_files["train"] = args.train_file
+ extension = args.train_file.split(".")[-1]
+ if args.validation_file is not None:
+ data_files["validation"] = args.validation_file
+ extension = args.validation_file.split(".")[-1]
+ raw_datasets = load_dataset(extension, data_files=data_files)
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+ #
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ if args.config_name:
+ config = AutoConfig.from_pretrained(args.config_name, trust_remote_code=args.trust_remote_code)
+ elif args.model_name_or_path:
+ config = AutoConfig.from_pretrained(args.model_name_or_path, trust_remote_code=args.trust_remote_code)
+ else:
+ config = CONFIG_MAPPING[args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ if args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.tokenizer_name, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
+ )
+ elif args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.model_name_or_path, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
+ )
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if args.model_name_or_path:
+ model = AutoModelForSeq2SeqLM.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ trust_remote_code=args.trust_remote_code,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = AutoModelForSeq2SeqLM.from_config(config, trust_remote_code=args.trust_remote_code)
+
+ # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
+ # on a small vocab and want a smaller embedding size, remove this test.
+ embedding_size = model.get_input_embeddings().weight.shape[0]
+ if len(tokenizer) > embedding_size:
+ model.resize_token_embeddings(len(tokenizer))
+ if model.config.decoder_start_token_id is None:
+ raise ValueError("Make sure that `config.decoder_start_token_id` is correctly defined")
+
+ prefix = args.source_prefix if args.source_prefix is not None else ""
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ column_names = raw_datasets["train"].column_names
+
+ # Get the column names for input/target.
+ dataset_columns = summarization_name_mapping.get(args.dataset_name, None)
+ if args.text_column is None:
+ text_column = dataset_columns[0] if dataset_columns is not None else column_names[0]
+ else:
+ text_column = args.text_column
+ if text_column not in column_names:
+ raise ValueError(
+ f"--text_column' value '{args.text_column}' needs to be one of: {', '.join(column_names)}"
+ )
+ if args.summary_column is None:
+ summary_column = dataset_columns[1] if dataset_columns is not None else column_names[1]
+ else:
+ summary_column = args.summary_column
+ if summary_column not in column_names:
+ raise ValueError(
+ f"--summary_column' value '{args.summary_column}' needs to be one of: {', '.join(column_names)}"
+ )
+
+ if args.val_max_target_length is None:
+ args.val_max_target_length = args.max_target_length
+
+ # Temporarily set max_target_length for training.
+ max_target_length = args.max_target_length
+ padding = "max_length" if args.pad_to_max_length else False
+
+ def preprocess_function(examples):
+ inputs = examples[text_column]
+ targets = examples[summary_column]
+ inputs = [prefix + inp for inp in inputs]
+ model_inputs = tokenizer(inputs, max_length=args.max_source_length, padding=padding, truncation=True)
+
+ # Tokenize targets with the `text_target` keyword argument
+ labels = tokenizer(text_target=targets, max_length=max_target_length, padding=padding, truncation=True)
+
+ # If we are padding here, replace all tokenizer.pad_token_id in the labels by -100 when we want to ignore
+ # padding in the loss.
+ if padding == "max_length" and args.ignore_pad_token_for_loss:
+ labels["input_ids"] = [
+ [(l if l != tokenizer.pad_token_id else -100) for l in label] for label in labels["input_ids"]
+ ]
+
+ model_inputs["labels"] = labels["input_ids"]
+ return model_inputs
+
+ with accelerator.main_process_first():
+ train_dataset = raw_datasets["train"].map(
+ preprocess_function,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Running tokenizer on dataset",
+ )
+
+ # Temporarily set max_target_length for validation.
+ max_target_length = args.val_max_target_length
+ eval_dataset = raw_datasets["validation"].map(
+ preprocess_function,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Running tokenizer on dataset",
+ )
+
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 1):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ label_pad_token_id = -100 if args.ignore_pad_token_for_loss else tokenizer.pad_token_id
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+ data_collator = DataCollatorForSeq2Seq(
+ tokenizer,
+ model=model,
+ label_pad_token_id=label_pad_token_id,
+ pad_to_multiple_of=pad_to_multiple_of,
+ )
+
+ def postprocess_text(preds, labels):
+ preds = [pred.strip() for pred in preds]
+ labels = [label.strip() for label in labels]
+
+ # rougeLSum expects newline after each sentence
+ preds = ["\n".join(nltk.sent_tokenize(pred)) for pred in preds]
+ labels = ["\n".join(nltk.sent_tokenize(label)) for label in labels]
+
+ return preds, labels
+
+ train_dataloader = DataLoader(
+ train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
+ )
+ eval_dataloader = DataLoader(eval_dataset, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size)
+
+ # Optimizer
+ # Split weights in two groups, one with weight decay and the other not.
+ no_decay = ["bias", "LayerNorm.weight", "layer_norm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
+ num_training_steps=args.max_train_steps
+ if overrode_max_train_steps
+ else args.max_train_steps * accelerator.num_processes,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("summarization_no_trainer", experiment_config)
+
+ # Metric
+ metric = evaluate.load("rouge")
+
+ # Train!
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ checkpoint_path = args.resume_from_checkpoint
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ checkpoint_path = path
+ path = os.path.basename(checkpoint_path)
+
+ accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
+ accelerator.load_state(checkpoint_path)
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ completed_steps = resume_step // args.gradient_accumulation_steps
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We skip the first `n` batches in the dataloader when resuming from a checkpoint
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ with accelerator.accumulate(model):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ accelerator.backward(loss)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # Checks if the accelerator has performed an optimization step behind the scenes
+ if accelerator.sync_gradients:
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if completed_steps >= args.max_train_steps:
+ break
+
+ model.eval()
+
+ gen_kwargs = {
+ "max_length": args.val_max_target_length,
+ "num_beams": args.num_beams,
+ }
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ generated_tokens = accelerator.unwrap_model(model).generate(
+ batch["input_ids"],
+ attention_mask=batch["attention_mask"],
+ **gen_kwargs,
+ )
+
+ generated_tokens = accelerator.pad_across_processes(
+ generated_tokens, dim=1, pad_index=tokenizer.pad_token_id
+ )
+ labels = batch["labels"]
+ if not args.pad_to_max_length:
+ # If we did not pad to max length, we need to pad the labels too
+ labels = accelerator.pad_across_processes(batch["labels"], dim=1, pad_index=tokenizer.pad_token_id)
+
+ generated_tokens, labels = accelerator.gather_for_metrics((generated_tokens, labels))
+ generated_tokens = generated_tokens.cpu().numpy()
+ labels = labels.cpu().numpy()
+
+ if args.ignore_pad_token_for_loss:
+ # Replace -100 in the labels as we can't decode them.
+ labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
+ if isinstance(generated_tokens, tuple):
+ generated_tokens = generated_tokens[0]
+ decoded_preds = tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+ decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+ decoded_preds, decoded_labels = postprocess_text(decoded_preds, decoded_labels)
+ metric.add_batch(
+ predictions=decoded_preds,
+ references=decoded_labels,
+ )
+ result = metric.compute(use_stemmer=True)
+ result = {k: round(v * 100, 4) for k, v in result.items()}
+
+ logger.info(result)
+
+ if args.with_tracking:
+ result["train_loss"] = total_loss.item() / len(train_dataloader)
+ result["epoch"] = epoch
+ result["step"] = completed_steps
+ accelerator.log(result, step=completed_steps)
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if args.checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ if args.push_to_hub:
+ api.upload_folder(
+ commit_message="End of training",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ all_results = {f"eval_{k}": v for k, v in result.items()}
+ with open(os.path.join(args.output_dir, "all_results.json"), "w") as f:
+ json.dump(all_results, f)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/test_accelerate_examples.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/test_accelerate_examples.py
new file mode 100644
index 0000000000000000000000000000000000000000..fe700eabdd925106a1cce7867b301057576e9326
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/test_accelerate_examples.py
@@ -0,0 +1,383 @@
+# coding=utf-8
+# Copyright 2018 HuggingFace Inc..
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+
+import argparse
+import json
+import logging
+import os
+import shutil
+import sys
+import tempfile
+import unittest
+from unittest import mock
+
+from accelerate.utils import write_basic_config
+
+from transformers.testing_utils import (
+ TestCasePlus,
+ backend_device_count,
+ run_command,
+ slow,
+ torch_device,
+)
+
+
+logging.basicConfig(level=logging.DEBUG)
+
+logger = logging.getLogger()
+
+
+def get_setup_file():
+ parser = argparse.ArgumentParser()
+ parser.add_argument("-f")
+ args = parser.parse_args()
+ return args.f
+
+
+def get_results(output_dir):
+ results = {}
+ path = os.path.join(output_dir, "all_results.json")
+ if os.path.exists(path):
+ with open(path, "r") as f:
+ results = json.load(f)
+ else:
+ raise ValueError(f"can't find {path}")
+ return results
+
+
+stream_handler = logging.StreamHandler(sys.stdout)
+logger.addHandler(stream_handler)
+
+
+class ExamplesTestsNoTrainer(TestCasePlus):
+ @classmethod
+ def setUpClass(cls):
+ # Write Accelerate config, will pick up on CPU, GPU, and multi-GPU
+ cls.tmpdir = tempfile.mkdtemp()
+ cls.configPath = os.path.join(cls.tmpdir, "default_config.yml")
+ write_basic_config(save_location=cls.configPath)
+ cls._launch_args = ["accelerate", "launch", "--config_file", cls.configPath]
+
+ @classmethod
+ def tearDownClass(cls):
+ shutil.rmtree(cls.tmpdir)
+
+ @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
+ def test_run_glue_no_trainer(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ {self.examples_dir}/pytorch/text-classification/run_glue_no_trainer.py
+ --model_name_or_path distilbert/distilbert-base-uncased
+ --output_dir {tmp_dir}
+ --train_file ./tests/fixtures/tests_samples/MRPC/train.csv
+ --validation_file ./tests/fixtures/tests_samples/MRPC/dev.csv
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --learning_rate=1e-4
+ --seed=42
+ --num_warmup_steps=2
+ --checkpointing_steps epoch
+ --with_tracking
+ """.split()
+
+ run_command(self._launch_args + testargs)
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_accuracy"], 0.75)
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "epoch_0")))
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "glue_no_trainer")))
+
+ @unittest.skip("Zach is working on this.")
+ @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
+ def test_run_clm_no_trainer(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ {self.examples_dir}/pytorch/language-modeling/run_clm_no_trainer.py
+ --model_name_or_path distilbert/distilgpt2
+ --train_file ./tests/fixtures/sample_text.txt
+ --validation_file ./tests/fixtures/sample_text.txt
+ --block_size 128
+ --per_device_train_batch_size 5
+ --per_device_eval_batch_size 5
+ --num_train_epochs 2
+ --output_dir {tmp_dir}
+ --checkpointing_steps epoch
+ --with_tracking
+ """.split()
+
+ if backend_device_count(torch_device) > 1:
+ # Skipping because there are not enough batches to train the model + would need a drop_last to work.
+ return
+
+ run_command(self._launch_args + testargs)
+ result = get_results(tmp_dir)
+ self.assertLess(result["perplexity"], 100)
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "epoch_0")))
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "clm_no_trainer")))
+
+ @unittest.skip("Zach is working on this.")
+ @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
+ def test_run_mlm_no_trainer(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ {self.examples_dir}/pytorch/language-modeling/run_mlm_no_trainer.py
+ --model_name_or_path distilbert/distilroberta-base
+ --train_file ./tests/fixtures/sample_text.txt
+ --validation_file ./tests/fixtures/sample_text.txt
+ --output_dir {tmp_dir}
+ --num_train_epochs=1
+ --checkpointing_steps epoch
+ --with_tracking
+ """.split()
+
+ run_command(self._launch_args + testargs)
+ result = get_results(tmp_dir)
+ self.assertLess(result["perplexity"], 42)
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "epoch_0")))
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "mlm_no_trainer")))
+
+ @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
+ def test_run_ner_no_trainer(self):
+ # with so little data distributed training needs more epochs to get the score on par with 0/1 gpu
+ epochs = 7 if backend_device_count(torch_device) > 1 else 2
+
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ {self.examples_dir}/pytorch/token-classification/run_ner_no_trainer.py
+ --model_name_or_path google-bert/bert-base-uncased
+ --train_file tests/fixtures/tests_samples/conll/sample.json
+ --validation_file tests/fixtures/tests_samples/conll/sample.json
+ --output_dir {tmp_dir}
+ --learning_rate=2e-4
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=2
+ --num_train_epochs={epochs}
+ --seed 7
+ --checkpointing_steps epoch
+ --with_tracking
+ """.split()
+
+ run_command(self._launch_args + testargs)
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_accuracy"], 0.75)
+ self.assertLess(result["train_loss"], 0.6)
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "epoch_0")))
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "ner_no_trainer")))
+
+ @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
+ def test_run_squad_no_trainer(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ {self.examples_dir}/pytorch/question-answering/run_qa_no_trainer.py
+ --model_name_or_path google-bert/bert-base-uncased
+ --version_2_with_negative
+ --train_file tests/fixtures/tests_samples/SQUAD/sample.json
+ --validation_file tests/fixtures/tests_samples/SQUAD/sample.json
+ --output_dir {tmp_dir}
+ --seed=42
+ --max_train_steps=10
+ --num_warmup_steps=2
+ --learning_rate=2e-4
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --checkpointing_steps epoch
+ --with_tracking
+ """.split()
+
+ run_command(self._launch_args + testargs)
+ result = get_results(tmp_dir)
+ # Because we use --version_2_with_negative the testing script uses SQuAD v2 metrics.
+ self.assertGreaterEqual(result["eval_f1"], 28)
+ self.assertGreaterEqual(result["eval_exact"], 28)
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "epoch_0")))
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "qa_no_trainer")))
+
+ @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
+ def test_run_swag_no_trainer(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ {self.examples_dir}/pytorch/multiple-choice/run_swag_no_trainer.py
+ --model_name_or_path google-bert/bert-base-uncased
+ --train_file tests/fixtures/tests_samples/swag/sample.json
+ --validation_file tests/fixtures/tests_samples/swag/sample.json
+ --output_dir {tmp_dir}
+ --max_train_steps=20
+ --num_warmup_steps=2
+ --learning_rate=2e-4
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --with_tracking
+ """.split()
+
+ run_command(self._launch_args + testargs)
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_accuracy"], 0.8)
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "swag_no_trainer")))
+
+ @slow
+ @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
+ def test_run_summarization_no_trainer(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ {self.examples_dir}/pytorch/summarization/run_summarization_no_trainer.py
+ --model_name_or_path google-t5/t5-small
+ --train_file tests/fixtures/tests_samples/xsum/sample.json
+ --validation_file tests/fixtures/tests_samples/xsum/sample.json
+ --output_dir {tmp_dir}
+ --max_train_steps=50
+ --num_warmup_steps=8
+ --learning_rate=2e-4
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --checkpointing_steps epoch
+ --with_tracking
+ """.split()
+
+ run_command(self._launch_args + testargs)
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_rouge1"], 10)
+ self.assertGreaterEqual(result["eval_rouge2"], 2)
+ self.assertGreaterEqual(result["eval_rougeL"], 7)
+ self.assertGreaterEqual(result["eval_rougeLsum"], 7)
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "epoch_0")))
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "summarization_no_trainer")))
+
+ @slow
+ @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
+ def test_run_translation_no_trainer(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ {self.examples_dir}/pytorch/translation/run_translation_no_trainer.py
+ --model_name_or_path sshleifer/student_marian_en_ro_6_1
+ --source_lang en
+ --target_lang ro
+ --train_file tests/fixtures/tests_samples/wmt16/sample.json
+ --validation_file tests/fixtures/tests_samples/wmt16/sample.json
+ --output_dir {tmp_dir}
+ --max_train_steps=50
+ --num_warmup_steps=8
+ --num_beams=6
+ --learning_rate=3e-3
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --source_lang en_XX
+ --target_lang ro_RO
+ --checkpointing_steps epoch
+ --with_tracking
+ """.split()
+
+ run_command(self._launch_args + testargs)
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_bleu"], 30)
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "epoch_0")))
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "translation_no_trainer")))
+
+ @slow
+ def test_run_semantic_segmentation_no_trainer(self):
+ stream_handler = logging.StreamHandler(sys.stdout)
+ logger.addHandler(stream_handler)
+
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ {self.examples_dir}/pytorch/semantic-segmentation/run_semantic_segmentation_no_trainer.py
+ --dataset_name huggingface/semantic-segmentation-test-sample
+ --output_dir {tmp_dir}
+ --max_train_steps=10
+ --num_warmup_steps=2
+ --learning_rate=2e-4
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --checkpointing_steps epoch
+ """.split()
+
+ run_command(self._launch_args + testargs)
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_overall_accuracy"], 0.10)
+
+ @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
+ def test_run_image_classification_no_trainer(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ {self.examples_dir}/pytorch/image-classification/run_image_classification_no_trainer.py
+ --model_name_or_path google/vit-base-patch16-224-in21k
+ --dataset_name hf-internal-testing/cats_vs_dogs_sample
+ --trust_remote_code
+ --learning_rate 1e-4
+ --per_device_train_batch_size 2
+ --per_device_eval_batch_size 1
+ --max_train_steps 2
+ --train_val_split 0.1
+ --seed 42
+ --output_dir {tmp_dir}
+ --with_tracking
+ --checkpointing_steps 1
+ --label_column_name labels
+ """.split()
+
+ run_command(self._launch_args + testargs)
+ result = get_results(tmp_dir)
+ # The base model scores a 25%
+ self.assertGreaterEqual(result["eval_accuracy"], 0.4)
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "step_1")))
+ self.assertTrue(os.path.exists(os.path.join(tmp_dir, "image_classification_no_trainer")))
+
+ @slow
+ @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
+ def test_run_object_detection_no_trainer(self):
+ stream_handler = logging.StreamHandler(sys.stdout)
+ logger.addHandler(stream_handler)
+
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ {self.examples_dir}/pytorch/object-detection/run_object_detection_no_trainer.py
+ --model_name_or_path qubvel-hf/detr-resnet-50-finetuned-10k-cppe5
+ --dataset_name qubvel-hf/cppe-5-sample
+ --output_dir {tmp_dir}
+ --max_train_steps=10
+ --num_warmup_steps=2
+ --learning_rate=1e-6
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --checkpointing_steps epoch
+ """.split()
+
+ run_command(self._launch_args + testargs)
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["test_map"], 0.10)
+
+ @slow
+ @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
+ def test_run_instance_segmentation_no_trainer(self):
+ stream_handler = logging.StreamHandler(sys.stdout)
+ logger.addHandler(stream_handler)
+
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ {self.examples_dir}/pytorch/instance-segmentation/run_instance_segmentation_no_trainer.py
+ --model_name_or_path qubvel-hf/finetune-instance-segmentation-ade20k-mini-mask2former
+ --output_dir {tmp_dir}
+ --dataset_name qubvel-hf/ade20k-nano
+ --do_reduce_labels
+ --image_height 256
+ --image_width 256
+ --num_train_epochs 1
+ --per_device_train_batch_size 2
+ --per_device_eval_batch_size 1
+ --seed 1234
+ """.split()
+
+ run_command(self._launch_args + testargs)
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["test_map"], 0.1)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/test_pytorch_examples.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/test_pytorch_examples.py
new file mode 100644
index 0000000000000000000000000000000000000000..c609ee860c728f69b1f75cef9c3f17065710193e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/test_pytorch_examples.py
@@ -0,0 +1,680 @@
+# coding=utf-8
+# Copyright 2018 HuggingFace Inc..
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+
+import json
+import logging
+import os
+import sys
+from unittest.mock import patch
+
+from transformers import ViTMAEForPreTraining, Wav2Vec2ForPreTraining
+from transformers.testing_utils import (
+ CaptureLogger,
+ TestCasePlus,
+ backend_device_count,
+ is_torch_fp16_available_on_device,
+ slow,
+ torch_device,
+)
+
+
+SRC_DIRS = [
+ os.path.join(os.path.dirname(__file__), dirname)
+ for dirname in [
+ "text-generation",
+ "text-classification",
+ "token-classification",
+ "language-modeling",
+ "multiple-choice",
+ "question-answering",
+ "summarization",
+ "translation",
+ "image-classification",
+ "speech-recognition",
+ "audio-classification",
+ "speech-pretraining",
+ "image-pretraining",
+ "semantic-segmentation",
+ "object-detection",
+ "instance-segmentation",
+ ]
+]
+sys.path.extend(SRC_DIRS)
+
+
+if SRC_DIRS is not None:
+ import run_audio_classification
+ import run_clm
+ import run_generation
+ import run_glue
+ import run_image_classification
+ import run_instance_segmentation
+ import run_mae
+ import run_mlm
+ import run_ner
+ import run_object_detection
+ import run_qa as run_squad
+ import run_semantic_segmentation
+ import run_seq2seq_qa as run_squad_seq2seq
+ import run_speech_recognition_ctc
+ import run_speech_recognition_ctc_adapter
+ import run_speech_recognition_seq2seq
+ import run_summarization
+ import run_swag
+ import run_translation
+ import run_wav2vec2_pretraining_no_trainer
+
+
+logging.basicConfig(level=logging.DEBUG)
+
+logger = logging.getLogger()
+
+
+def get_results(output_dir):
+ results = {}
+ path = os.path.join(output_dir, "all_results.json")
+ if os.path.exists(path):
+ with open(path, "r") as f:
+ results = json.load(f)
+ else:
+ raise ValueError(f"can't find {path}")
+ return results
+
+
+stream_handler = logging.StreamHandler(sys.stdout)
+logger.addHandler(stream_handler)
+
+
+class ExamplesTests(TestCasePlus):
+ def test_run_glue(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_glue.py
+ --model_name_or_path distilbert/distilbert-base-uncased
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ --train_file ./tests/fixtures/tests_samples/MRPC/train.csv
+ --validation_file ./tests/fixtures/tests_samples/MRPC/dev.csv
+ --do_train
+ --do_eval
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --learning_rate=1e-4
+ --max_steps=10
+ --warmup_steps=2
+ --seed=42
+ --max_seq_length=128
+ """.split()
+
+ if is_torch_fp16_available_on_device(torch_device):
+ testargs.append("--fp16")
+
+ with patch.object(sys, "argv", testargs):
+ run_glue.main()
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_accuracy"], 0.75)
+
+ def test_run_clm(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_clm.py
+ --model_name_or_path distilbert/distilgpt2
+ --train_file ./tests/fixtures/sample_text.txt
+ --validation_file ./tests/fixtures/sample_text.txt
+ --do_train
+ --do_eval
+ --block_size 128
+ --per_device_train_batch_size 5
+ --per_device_eval_batch_size 5
+ --num_train_epochs 2
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ """.split()
+
+ if backend_device_count(torch_device) > 1:
+ # Skipping because there are not enough batches to train the model + would need a drop_last to work.
+ return
+
+ if torch_device == "cpu":
+ testargs.append("--use_cpu")
+
+ with patch.object(sys, "argv", testargs):
+ run_clm.main()
+ result = get_results(tmp_dir)
+ self.assertLess(result["perplexity"], 100)
+
+ def test_run_clm_config_overrides(self):
+ # test that config_overrides works, despite the misleading dumps of default un-updated
+ # config via tokenizer
+
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_clm.py
+ --model_type gpt2
+ --tokenizer_name openai-community/gpt2
+ --train_file ./tests/fixtures/sample_text.txt
+ --output_dir {tmp_dir}
+ --config_overrides n_embd=10,n_head=2
+ """.split()
+
+ if torch_device == "cpu":
+ testargs.append("--use_cpu")
+
+ logger = run_clm.logger
+ with patch.object(sys, "argv", testargs):
+ with CaptureLogger(logger) as cl:
+ run_clm.main()
+
+ self.assertIn('"n_embd": 10', cl.out)
+ self.assertIn('"n_head": 2', cl.out)
+
+ def test_run_mlm(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_mlm.py
+ --model_name_or_path distilbert/distilroberta-base
+ --train_file ./tests/fixtures/sample_text.txt
+ --validation_file ./tests/fixtures/sample_text.txt
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ --do_train
+ --do_eval
+ --prediction_loss_only
+ --num_train_epochs=1
+ """.split()
+
+ if torch_device == "cpu":
+ testargs.append("--use_cpu")
+
+ with patch.object(sys, "argv", testargs):
+ run_mlm.main()
+ result = get_results(tmp_dir)
+ self.assertLess(result["perplexity"], 42)
+
+ def test_run_ner(self):
+ # with so little data distributed training needs more epochs to get the score on par with 0/1 gpu
+ epochs = 7 if backend_device_count(torch_device) > 1 else 2
+
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_ner.py
+ --model_name_or_path google-bert/bert-base-uncased
+ --train_file tests/fixtures/tests_samples/conll/sample.json
+ --validation_file tests/fixtures/tests_samples/conll/sample.json
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ --do_train
+ --do_eval
+ --warmup_steps=2
+ --learning_rate=2e-4
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=2
+ --num_train_epochs={epochs}
+ --seed 7
+ """.split()
+
+ if torch_device == "cpu":
+ testargs.append("--use_cpu")
+
+ with patch.object(sys, "argv", testargs):
+ run_ner.main()
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_accuracy"], 0.75)
+ self.assertLess(result["eval_loss"], 0.5)
+
+ def test_run_squad(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_qa.py
+ --model_name_or_path google-bert/bert-base-uncased
+ --version_2_with_negative
+ --train_file tests/fixtures/tests_samples/SQUAD/sample.json
+ --validation_file tests/fixtures/tests_samples/SQUAD/sample.json
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ --max_steps=10
+ --warmup_steps=2
+ --do_train
+ --do_eval
+ --learning_rate=2e-4
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ run_squad.main()
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_f1"], 30)
+ self.assertGreaterEqual(result["eval_exact"], 30)
+
+ def test_run_squad_seq2seq(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_seq2seq_qa.py
+ --model_name_or_path google-t5/t5-small
+ --context_column context
+ --question_column question
+ --answer_column answers
+ --version_2_with_negative
+ --train_file tests/fixtures/tests_samples/SQUAD/sample.json
+ --validation_file tests/fixtures/tests_samples/SQUAD/sample.json
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ --max_steps=10
+ --warmup_steps=2
+ --do_train
+ --do_eval
+ --learning_rate=2e-4
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --predict_with_generate
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ run_squad_seq2seq.main()
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_f1"], 30)
+ self.assertGreaterEqual(result["eval_exact"], 30)
+
+ def test_run_swag(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_swag.py
+ --model_name_or_path google-bert/bert-base-uncased
+ --train_file tests/fixtures/tests_samples/swag/sample.json
+ --validation_file tests/fixtures/tests_samples/swag/sample.json
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ --max_steps=20
+ --warmup_steps=2
+ --do_train
+ --do_eval
+ --learning_rate=2e-4
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ run_swag.main()
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_accuracy"], 0.8)
+
+ def test_generation(self):
+ testargs = ["run_generation.py", "--prompt=Hello", "--length=10", "--seed=42"]
+
+ if is_torch_fp16_available_on_device(torch_device):
+ testargs.append("--fp16")
+
+ model_type, model_name = (
+ "--model_type=gpt2",
+ "--model_name_or_path=sshleifer/tiny-gpt2",
+ )
+ with patch.object(sys, "argv", testargs + [model_type, model_name]):
+ result = run_generation.main()
+ self.assertGreaterEqual(len(result[0]), 10)
+
+ @slow
+ def test_run_summarization(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_summarization.py
+ --model_name_or_path google-t5/t5-small
+ --train_file tests/fixtures/tests_samples/xsum/sample.json
+ --validation_file tests/fixtures/tests_samples/xsum/sample.json
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ --max_steps=50
+ --warmup_steps=8
+ --do_train
+ --do_eval
+ --learning_rate=2e-4
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --predict_with_generate
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ run_summarization.main()
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_rouge1"], 10)
+ self.assertGreaterEqual(result["eval_rouge2"], 2)
+ self.assertGreaterEqual(result["eval_rougeL"], 7)
+ self.assertGreaterEqual(result["eval_rougeLsum"], 7)
+
+ @slow
+ def test_run_translation(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_translation.py
+ --model_name_or_path sshleifer/student_marian_en_ro_6_1
+ --source_lang en
+ --target_lang ro
+ --train_file tests/fixtures/tests_samples/wmt16/sample.json
+ --validation_file tests/fixtures/tests_samples/wmt16/sample.json
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ --max_steps=50
+ --warmup_steps=8
+ --do_train
+ --do_eval
+ --learning_rate=3e-3
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --predict_with_generate
+ --source_lang en_XX
+ --target_lang ro_RO
+ --max_source_length 512
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ run_translation.main()
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_bleu"], 30)
+
+ def test_run_image_classification(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_image_classification.py
+ --output_dir {tmp_dir}
+ --model_name_or_path google/vit-base-patch16-224-in21k
+ --dataset_name hf-internal-testing/cats_vs_dogs_sample
+ --trust_remote_code
+ --do_train
+ --do_eval
+ --learning_rate 1e-4
+ --per_device_train_batch_size 2
+ --per_device_eval_batch_size 1
+ --remove_unused_columns False
+ --overwrite_output_dir True
+ --dataloader_num_workers 16
+ --metric_for_best_model accuracy
+ --max_steps 10
+ --train_val_split 0.1
+ --seed 42
+ --label_column_name labels
+ """.split()
+
+ if is_torch_fp16_available_on_device(torch_device):
+ testargs.append("--fp16")
+
+ with patch.object(sys, "argv", testargs):
+ run_image_classification.main()
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_accuracy"], 0.8)
+
+ def test_run_speech_recognition_ctc(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_speech_recognition_ctc.py
+ --output_dir {tmp_dir}
+ --model_name_or_path hf-internal-testing/tiny-random-wav2vec2
+ --dataset_name hf-internal-testing/librispeech_asr_dummy
+ --dataset_config_name clean
+ --train_split_name validation
+ --eval_split_name validation
+ --trust_remote_code
+ --do_train
+ --do_eval
+ --learning_rate 1e-4
+ --per_device_train_batch_size 2
+ --per_device_eval_batch_size 1
+ --remove_unused_columns False
+ --overwrite_output_dir True
+ --preprocessing_num_workers 16
+ --max_steps 10
+ --seed 42
+ """.split()
+
+ if is_torch_fp16_available_on_device(torch_device):
+ testargs.append("--fp16")
+
+ with patch.object(sys, "argv", testargs):
+ run_speech_recognition_ctc.main()
+ result = get_results(tmp_dir)
+ self.assertLess(result["eval_loss"], result["train_loss"])
+
+ def test_run_speech_recognition_ctc_adapter(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_speech_recognition_ctc_adapter.py
+ --output_dir {tmp_dir}
+ --model_name_or_path hf-internal-testing/tiny-random-wav2vec2
+ --dataset_name hf-internal-testing/librispeech_asr_dummy
+ --dataset_config_name clean
+ --train_split_name validation
+ --eval_split_name validation
+ --trust_remote_code
+ --do_train
+ --do_eval
+ --learning_rate 1e-4
+ --per_device_train_batch_size 2
+ --per_device_eval_batch_size 1
+ --remove_unused_columns False
+ --overwrite_output_dir True
+ --preprocessing_num_workers 16
+ --max_steps 10
+ --target_language tur
+ --seed 42
+ """.split()
+
+ if is_torch_fp16_available_on_device(torch_device):
+ testargs.append("--fp16")
+
+ with patch.object(sys, "argv", testargs):
+ run_speech_recognition_ctc_adapter.main()
+ result = get_results(tmp_dir)
+ self.assertTrue(os.path.isfile(os.path.join(tmp_dir, "./adapter.tur.safetensors")))
+ self.assertLess(result["eval_loss"], result["train_loss"])
+
+ def test_run_speech_recognition_seq2seq(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_speech_recognition_seq2seq.py
+ --output_dir {tmp_dir}
+ --model_name_or_path hf-internal-testing/tiny-random-speech-encoder-decoder
+ --dataset_name hf-internal-testing/librispeech_asr_dummy
+ --dataset_config_name clean
+ --train_split_name validation
+ --eval_split_name validation
+ --trust_remote_code
+ --do_train
+ --do_eval
+ --learning_rate 1e-4
+ --per_device_train_batch_size 2
+ --per_device_eval_batch_size 4
+ --remove_unused_columns False
+ --overwrite_output_dir True
+ --preprocessing_num_workers 16
+ --max_steps 10
+ --seed 42
+ """.split()
+
+ if is_torch_fp16_available_on_device(torch_device):
+ testargs.append("--fp16")
+
+ with patch.object(sys, "argv", testargs):
+ run_speech_recognition_seq2seq.main()
+ result = get_results(tmp_dir)
+ self.assertLess(result["eval_loss"], result["train_loss"])
+
+ def test_run_audio_classification(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_audio_classification.py
+ --output_dir {tmp_dir}
+ --model_name_or_path hf-internal-testing/tiny-random-wav2vec2
+ --dataset_name anton-l/superb_demo
+ --trust_remote_code
+ --dataset_config_name ks
+ --train_split_name test
+ --eval_split_name test
+ --audio_column_name audio
+ --label_column_name label
+ --do_train
+ --do_eval
+ --learning_rate 1e-4
+ --per_device_train_batch_size 2
+ --per_device_eval_batch_size 1
+ --remove_unused_columns False
+ --overwrite_output_dir True
+ --num_train_epochs 10
+ --max_steps 50
+ --seed 42
+ """.split()
+
+ if is_torch_fp16_available_on_device(torch_device):
+ testargs.append("--fp16")
+
+ with patch.object(sys, "argv", testargs):
+ run_audio_classification.main()
+ result = get_results(tmp_dir)
+ self.assertLess(result["eval_loss"], result["train_loss"])
+
+ def test_run_wav2vec2_pretraining(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_wav2vec2_pretraining_no_trainer.py
+ --output_dir {tmp_dir}
+ --model_name_or_path hf-internal-testing/tiny-random-wav2vec2
+ --dataset_name hf-internal-testing/librispeech_asr_dummy
+ --dataset_config_names clean
+ --dataset_split_names validation
+ --trust_remote_code
+ --learning_rate 1e-4
+ --per_device_train_batch_size 4
+ --per_device_eval_batch_size 4
+ --preprocessing_num_workers 16
+ --max_train_steps 2
+ --validation_split_percentage 5
+ --seed 42
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ run_wav2vec2_pretraining_no_trainer.main()
+ model = Wav2Vec2ForPreTraining.from_pretrained(tmp_dir)
+ self.assertIsNotNone(model)
+
+ def test_run_vit_mae_pretraining(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_mae.py
+ --output_dir {tmp_dir}
+ --dataset_name hf-internal-testing/cats_vs_dogs_sample
+ --trust_remote_code
+ --do_train
+ --do_eval
+ --learning_rate 1e-4
+ --per_device_train_batch_size 2
+ --per_device_eval_batch_size 1
+ --remove_unused_columns False
+ --overwrite_output_dir True
+ --dataloader_num_workers 16
+ --metric_for_best_model accuracy
+ --max_steps 10
+ --train_val_split 0.1
+ --seed 42
+ """.split()
+
+ if is_torch_fp16_available_on_device(torch_device):
+ testargs.append("--fp16")
+
+ with patch.object(sys, "argv", testargs):
+ run_mae.main()
+ model = ViTMAEForPreTraining.from_pretrained(tmp_dir)
+ self.assertIsNotNone(model)
+
+ def test_run_semantic_segmentation(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_semantic_segmentation.py
+ --output_dir {tmp_dir}
+ --dataset_name huggingface/semantic-segmentation-test-sample
+ --do_train
+ --do_eval
+ --remove_unused_columns False
+ --overwrite_output_dir True
+ --max_steps 10
+ --learning_rate=2e-4
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --seed 32
+ """.split()
+
+ if is_torch_fp16_available_on_device(torch_device):
+ testargs.append("--fp16")
+
+ with patch.object(sys, "argv", testargs):
+ run_semantic_segmentation.main()
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["eval_overall_accuracy"], 0.1)
+
+ @patch.dict(os.environ, {"WANDB_DISABLED": "true"})
+ def test_run_object_detection(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_object_detection.py
+ --model_name_or_path qubvel-hf/detr-resnet-50-finetuned-10k-cppe5
+ --output_dir {tmp_dir}
+ --dataset_name qubvel-hf/cppe-5-sample
+ --do_train
+ --do_eval
+ --remove_unused_columns False
+ --overwrite_output_dir True
+ --eval_do_concat_batches False
+ --max_steps 10
+ --learning_rate=1e-6
+ --per_device_train_batch_size=2
+ --per_device_eval_batch_size=1
+ --seed 32
+ """.split()
+
+ if is_torch_fp16_available_on_device(torch_device):
+ testargs.append("--fp16")
+
+ with patch.object(sys, "argv", testargs):
+ run_object_detection.main()
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["test_map"], 0.1)
+
+ @patch.dict(os.environ, {"WANDB_DISABLED": "true"})
+ def test_run_instance_segmentation(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_instance_segmentation.py
+ --model_name_or_path qubvel-hf/finetune-instance-segmentation-ade20k-mini-mask2former
+ --output_dir {tmp_dir}
+ --dataset_name qubvel-hf/ade20k-nano
+ --do_reduce_labels
+ --image_height 256
+ --image_width 256
+ --do_train
+ --num_train_epochs 1
+ --learning_rate 1e-5
+ --lr_scheduler_type constant
+ --per_device_train_batch_size 2
+ --per_device_eval_batch_size 1
+ --do_eval
+ --evaluation_strategy epoch
+ --seed 32
+ """.split()
+
+ if is_torch_fp16_available_on_device(torch_device):
+ testargs.append("--fp16")
+
+ with patch.object(sys, "argv", testargs):
+ run_instance_segmentation.main()
+ result = get_results(tmp_dir)
+ self.assertGreaterEqual(result["test_map"], 0.1)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..6eae65e7c4bc5122f676980058e81a5aca40518a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/README.md
@@ -0,0 +1,252 @@
+
+
+# Text classification examples
+
+## GLUE tasks
+
+Based on the script [`run_glue.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-classification/run_glue.py).
+
+Fine-tuning the library models for sequence classification on the GLUE benchmark: [General Language Understanding
+Evaluation](https://gluebenchmark.com/). This script can fine-tune any of the models on the [hub](https://huggingface.co/models)
+and can also be used for a dataset hosted on our [hub](https://huggingface.co/datasets) or your own data in a csv or a JSON file
+(the script might need some tweaks in that case, refer to the comments inside for help).
+
+GLUE is made up of a total of 9 different tasks. Here is how to run the script on one of them:
+
+```bash
+export TASK_NAME=mrpc
+
+python run_glue.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --task_name $TASK_NAME \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 32 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/
+```
+
+where task name can be one of cola, sst2, mrpc, stsb, qqp, mnli, qnli, rte, wnli.
+
+We get the following results on the dev set of the benchmark with the previous commands (with an exception for MRPC and
+WNLI which are tiny and where we used 5 epochs instead of 3). Trainings are seeded so you should obtain the same
+results with PyTorch 1.6.0 (and close results with different versions), training times are given for information (a
+single Titan RTX was used):
+
+| Task | Metric | Result | Training time |
+|-------|------------------------------|-------------|---------------|
+| CoLA | Matthews corr | 56.53 | 3:17 |
+| SST-2 | Accuracy | 92.32 | 26:06 |
+| MRPC | F1/Accuracy | 88.85/84.07 | 2:21 |
+| STS-B | Pearson/Spearman corr. | 88.64/88.48 | 2:13 |
+| QQP | Accuracy/F1 | 90.71/87.49 | 2:22:26 |
+| MNLI | Matched acc./Mismatched acc. | 83.91/84.10 | 2:35:23 |
+| QNLI | Accuracy | 90.66 | 40:57 |
+| RTE | Accuracy | 65.70 | 57 |
+| WNLI | Accuracy | 56.34 | 24 |
+
+Some of these results are significantly different from the ones reported on the test set of GLUE benchmark on the
+website. For QQP and WNLI, please refer to [FAQ #12](https://gluebenchmark.com/faq) on the website.
+
+The following example fine-tunes BERT on the `imdb` dataset hosted on our [hub](https://huggingface.co/datasets):
+
+```bash
+python run_glue.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --dataset_name imdb \
+ --do_train \
+ --do_predict \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 32 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/imdb/
+```
+
+> If your model classification head dimensions do not fit the number of labels in the dataset, you can specify `--ignore_mismatched_sizes` to adapt it.
+
+## Text classification
+As an alternative, we can use the script [`run_classification.py`](./run_classification.py) to fine-tune models on a single/multi-label classification task.
+
+The following example fine-tunes BERT on the `en` subset of [`amazon_reviews_multi`](https://huggingface.co/datasets/amazon_reviews_multi) dataset.
+We can specify the metric, the label column and aso choose which text columns to use jointly for classification.
+```bash
+dataset="amazon_reviews_multi"
+subset="en"
+python run_classification.py \
+ --model_name_or_path google-bert/bert-base-uncased \
+ --dataset_name ${dataset} \
+ --dataset_config_name ${subset} \
+ --shuffle_train_dataset \
+ --metric_name accuracy \
+ --text_column_name "review_title,review_body,product_category" \
+ --text_column_delimiter "\n" \
+ --label_column_name stars \
+ --do_train \
+ --do_eval \
+ --max_seq_length 512 \
+ --per_device_train_batch_size 32 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 1 \
+ --output_dir /tmp/${dataset}_${subset}/
+```
+Training for 1 epoch results in acc of around 0.5958 for review_body only and 0.659 for title+body+category.
+
+The following is a multi-label classification example. It fine-tunes BERT on the `reuters21578` dataset hosted on our [hub](https://huggingface.co/datasets/reuters21578):
+```bash
+dataset="reuters21578"
+subset="ModApte"
+python run_classification.py \
+ --model_name_or_path google-bert/bert-base-uncased \
+ --dataset_name ${dataset} \
+ --dataset_config_name ${subset} \
+ --shuffle_train_dataset \
+ --remove_splits "unused" \
+ --metric_name f1 \
+ --text_column_name text \
+ --label_column_name topics \
+ --do_train \
+ --do_eval \
+ --max_seq_length 512 \
+ --per_device_train_batch_size 32 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 15 \
+ --output_dir /tmp/${dataset}_${subset}/
+```
+ It results in a Micro F1 score of around 0.82 without any text and label filtering. Note that you have to explicitly remove the "unused" split from the dataset, since it is not used for classification.
+
+### Mixed precision training
+
+If you have a GPU with mixed precision capabilities (architecture Pascal or more recent), you can use mixed precision
+training with PyTorch 1.6.0 or latest, or by installing the [Apex](https://github.com/NVIDIA/apex) library for previous
+versions. Just add the flag `--fp16` to your command launching one of the scripts mentioned above!
+
+Using mixed precision training usually results in 2x-speedup for training with the same final results:
+
+| Task | Metric | Result | Training time | Result (FP16) | Training time (FP16) |
+|-------|------------------------------|-------------|---------------|---------------|----------------------|
+| CoLA | Matthews corr | 56.53 | 3:17 | 56.78 | 1:41 |
+| SST-2 | Accuracy | 92.32 | 26:06 | 91.74 | 13:11 |
+| MRPC | F1/Accuracy | 88.85/84.07 | 2:21 | 88.12/83.58 | 1:10 |
+| STS-B | Pearson/Spearman corr. | 88.64/88.48 | 2:13 | 88.71/88.55 | 1:08 |
+| QQP | Accuracy/F1 | 90.71/87.49 | 2:22:26 | 90.67/87.43 | 1:11:54 |
+| MNLI | Matched acc./Mismatched acc. | 83.91/84.10 | 2:35:23 | 84.04/84.06 | 1:17:06 |
+| QNLI | Accuracy | 90.66 | 40:57 | 90.96 | 20:16 |
+| RTE | Accuracy | 65.70 | 57 | 65.34 | 29 |
+| WNLI | Accuracy | 56.34 | 24 | 56.34 | 12 |
+
+
+## PyTorch version, no Trainer
+
+Based on the script [`run_glue_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-classification/run_glue_no_trainer.py).
+
+Like `run_glue.py`, this script allows you to fine-tune any of the models on the [hub](https://huggingface.co/models) on a
+text classification task, either a GLUE task or your own data in a csv or a JSON file. The main difference is that this
+script exposes the bare training loop, to allow you to quickly experiment and add any customization you would like.
+
+It offers less options than the script with `Trainer` (for instance you can easily change the options for the optimizer
+or the dataloaders directly in the script) but still run in a distributed setup, on TPU and supports mixed precision by
+the mean of the [🤗 `Accelerate`](https://github.com/huggingface/accelerate) library. You can use the script normally
+after installing it:
+
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+then
+
+```bash
+export TASK_NAME=mrpc
+
+python run_glue_no_trainer.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --task_name $TASK_NAME \
+ --max_length 128 \
+ --per_device_train_batch_size 32 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/
+```
+
+You can then use your usual launchers to run in it in a distributed environment, but the easiest way is to run
+
+```bash
+accelerate config
+```
+
+and reply to the questions asked. Then
+
+```bash
+accelerate test
+```
+
+that will check everything is ready for training. Finally, you can launch training with
+
+```bash
+export TASK_NAME=mrpc
+
+accelerate launch run_glue_no_trainer.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --task_name $TASK_NAME \
+ --max_length 128 \
+ --per_device_train_batch_size 32 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/
+```
+
+This command is the same and will work for:
+
+- a CPU-only setup
+- a setup with one GPU
+- a distributed training with several GPUs (single or multi node)
+- a training on TPUs
+
+Note that this library is in alpha release so your feedback is more than welcome if you encounter any problem using it.
+
+## XNLI
+
+Based on the script [`run_xnli.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-classification/run_xnli.py).
+
+[XNLI](https://cims.nyu.edu/~sbowman/xnli/) is a crowd-sourced dataset based on [MultiNLI](https://cims.nyu.edu/~sbowman/multinli/). It is an evaluation benchmark for cross-lingual text representations. Pairs of text are labeled with textual entailment annotations for 15 different languages (including both high-resource language such as English and low-resource languages such as Swahili).
+
+#### Fine-tuning on XNLI
+
+This example code fine-tunes mBERT (multi-lingual BERT) on the XNLI dataset. It runs in 106 mins on a single tesla V100 16GB.
+
+```bash
+python run_xnli.py \
+ --model_name_or_path google-bert/bert-base-multilingual-cased \
+ --language de \
+ --train_language en \
+ --do_train \
+ --do_eval \
+ --per_device_train_batch_size 32 \
+ --learning_rate 5e-5 \
+ --num_train_epochs 2.0 \
+ --max_seq_length 128 \
+ --output_dir /tmp/debug_xnli/ \
+ --save_steps -1
+```
+
+Training with the previously defined hyper-parameters yields the following results on the **test** set:
+
+```bash
+acc = 0.7093812375249501
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..19090ab12477d9389cbc69804ef43180ce0e1f66
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/requirements.txt
@@ -0,0 +1,8 @@
+accelerate >= 0.12.0
+datasets >= 1.8.0
+sentencepiece != 0.1.92
+scipy
+scikit-learn
+protobuf
+torch >= 1.3
+evaluate
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/run_classification.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/run_classification.py
new file mode 100644
index 0000000000000000000000000000000000000000..fef77f4108a39da9b2947f0f8465a6dc2d768016
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/run_classification.py
@@ -0,0 +1,753 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2020 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Finetuning the library models for text classification."""
+# You can also adapt this script on your own text classification task. Pointers for this are left as comments.
+
+import logging
+import os
+import random
+import sys
+from dataclasses import dataclass, field
+from typing import List, Optional
+
+import datasets
+import evaluate
+import numpy as np
+from datasets import Value, load_dataset
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForSequenceClassification,
+ AutoTokenizer,
+ DataCollatorWithPadding,
+ EvalPrediction,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ default_data_collator,
+ set_seed,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/text-classification/requirements.txt")
+
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+
+ Using `HfArgumentParser` we can turn this class
+ into argparse arguments to be able to specify them on
+ the command line.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ do_regression: bool = field(
+ default=None,
+ metadata={
+ "help": "Whether to do regression instead of classification. If None, will be inferred from the dataset."
+ },
+ )
+ text_column_names: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The name of the text column in the input dataset or a CSV/JSON file. "
+ 'If not specified, will use the "sentence" column for single/multi-label classification task.'
+ )
+ },
+ )
+ text_column_delimiter: Optional[str] = field(
+ default=" ", metadata={"help": "The delimiter to use to join text columns into a single sentence."}
+ )
+ train_split_name: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": 'The name of the train split in the input dataset. If not specified, will use the "train" split when do_train is enabled'
+ },
+ )
+ validation_split_name: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": 'The name of the validation split in the input dataset. If not specified, will use the "validation" split when do_eval is enabled'
+ },
+ )
+ test_split_name: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": 'The name of the test split in the input dataset. If not specified, will use the "test" split when do_predict is enabled'
+ },
+ )
+ remove_splits: Optional[str] = field(
+ default=None,
+ metadata={"help": "The splits to remove from the dataset. Multiple splits should be separated by commas."},
+ )
+ remove_columns: Optional[str] = field(
+ default=None,
+ metadata={"help": "The columns to remove from the dataset. Multiple columns should be separated by commas."},
+ )
+ label_column_name: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The name of the label column in the input dataset or a CSV/JSON file. "
+ 'If not specified, will use the "label" column for single/multi-label classification task'
+ )
+ },
+ )
+ max_seq_length: int = field(
+ default=128,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached preprocessed datasets or not."}
+ )
+ pad_to_max_length: bool = field(
+ default=True,
+ metadata={
+ "help": (
+ "Whether to pad all samples to `max_seq_length`. "
+ "If False, will pad the samples dynamically when batching to the maximum length in the batch."
+ )
+ },
+ )
+ shuffle_train_dataset: bool = field(
+ default=False, metadata={"help": "Whether to shuffle the train dataset or not."}
+ )
+ shuffle_seed: int = field(
+ default=42, metadata={"help": "Random seed that will be used to shuffle the train dataset."}
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_predict_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of prediction examples to this "
+ "value if set."
+ )
+ },
+ )
+ metric_name: Optional[str] = field(default=None, metadata={"help": "The metric to use for evaluation."})
+ train_file: Optional[str] = field(
+ default=None, metadata={"help": "A csv or a json file containing the training data."}
+ )
+ validation_file: Optional[str] = field(
+ default=None, metadata={"help": "A csv or a json file containing the validation data."}
+ )
+ test_file: Optional[str] = field(default=None, metadata={"help": "A csv or a json file containing the test data."})
+
+ def __post_init__(self):
+ if self.dataset_name is None:
+ if self.train_file is None or self.validation_file is None:
+ raise ValueError(" training/validation file or a dataset name.")
+
+ train_extension = self.train_file.split(".")[-1]
+ assert train_extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ validation_extension = self.validation_file.split(".")[-1]
+ assert (
+ validation_extension == train_extension
+ ), "`validation_file` should have the same extension (csv or json) as `train_file`."
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ ignore_mismatched_sizes: bool = field(
+ default=False,
+ metadata={"help": "Will enable to load a pretrained model whose head dimensions are different."},
+ )
+
+
+def get_label_list(raw_dataset, split="train") -> List[str]:
+ """Get the list of labels from a multi-label dataset"""
+
+ if isinstance(raw_dataset[split]["label"][0], list):
+ label_list = [label for sample in raw_dataset[split]["label"] for label in sample]
+ label_list = list(set(label_list))
+ else:
+ label_list = raw_dataset[split].unique("label")
+ # we will treat the label list as a list of string instead of int, consistent with model.config.label2id
+ label_list = [str(label) for label in label_list]
+ return label_list
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_classification", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ datasets.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Get the datasets: you can either provide your own CSV/JSON training and evaluation files, or specify a dataset name
+ # to load from huggingface/datasets. In ether case, you can specify a the key of the column(s) containing the text and
+ # the key of the column containing the label. If multiple columns are specified for the text, they will be joined together
+ # for the actual text value.
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ # Try print some info about the dataset
+ logger.info(f"Dataset loaded: {raw_datasets}")
+ logger.info(raw_datasets)
+ else:
+ # Loading a dataset from your local files.
+ # CSV/JSON training and evaluation files are needed.
+ data_files = {"train": data_args.train_file, "validation": data_args.validation_file}
+
+ # Get the test dataset: you can provide your own CSV/JSON test file
+ if training_args.do_predict:
+ if data_args.test_file is not None:
+ train_extension = data_args.train_file.split(".")[-1]
+ test_extension = data_args.test_file.split(".")[-1]
+ assert (
+ test_extension == train_extension
+ ), "`test_file` should have the same extension (csv or json) as `train_file`."
+ data_files["test"] = data_args.test_file
+ else:
+ raise ValueError("Need either a dataset name or a test file for `do_predict`.")
+
+ for key in data_files.keys():
+ logger.info(f"load a local file for {key}: {data_files[key]}")
+
+ if data_args.train_file.endswith(".csv"):
+ # Loading a dataset from local csv files
+ raw_datasets = load_dataset(
+ "csv",
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ else:
+ # Loading a dataset from local json files
+ raw_datasets = load_dataset(
+ "json",
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+
+ # See more about loading any type of standard or custom dataset at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ if data_args.remove_splits is not None:
+ for split in data_args.remove_splits.split(","):
+ logger.info(f"removing split {split}")
+ raw_datasets.pop(split)
+
+ if data_args.train_split_name is not None:
+ logger.info(f"using {data_args.train_split_name} as train set")
+ raw_datasets["train"] = raw_datasets[data_args.train_split_name]
+ raw_datasets.pop(data_args.train_split_name)
+
+ if data_args.validation_split_name is not None:
+ logger.info(f"using {data_args.validation_split_name} as validation set")
+ raw_datasets["validation"] = raw_datasets[data_args.validation_split_name]
+ raw_datasets.pop(data_args.validation_split_name)
+
+ if data_args.test_split_name is not None:
+ logger.info(f"using {data_args.test_split_name} as test set")
+ raw_datasets["test"] = raw_datasets[data_args.test_split_name]
+ raw_datasets.pop(data_args.test_split_name)
+
+ if data_args.remove_columns is not None:
+ for split in raw_datasets.keys():
+ for column in data_args.remove_columns.split(","):
+ logger.info(f"removing column {column} from split {split}")
+ raw_datasets[split] = raw_datasets[split].remove_columns(column)
+
+ if data_args.label_column_name is not None and data_args.label_column_name != "label":
+ for key in raw_datasets.keys():
+ raw_datasets[key] = raw_datasets[key].rename_column(data_args.label_column_name, "label")
+
+ # Trying to have good defaults here, don't hesitate to tweak to your needs.
+
+ is_regression = (
+ raw_datasets["train"].features["label"].dtype in ["float32", "float64"]
+ if data_args.do_regression is None
+ else data_args.do_regression
+ )
+
+ is_multi_label = False
+ if is_regression:
+ label_list = None
+ num_labels = 1
+ # regession requires float as label type, let's cast it if needed
+ for split in raw_datasets.keys():
+ if raw_datasets[split].features["label"].dtype not in ["float32", "float64"]:
+ logger.warning(
+ f"Label type for {split} set to float32, was {raw_datasets[split].features['label'].dtype}"
+ )
+ features = raw_datasets[split].features
+ features.update({"label": Value("float32")})
+ try:
+ raw_datasets[split] = raw_datasets[split].cast(features)
+ except TypeError as error:
+ logger.error(
+ f"Unable to cast {split} set to float32, please check the labels are correct, or maybe try with --do_regression=False"
+ )
+ raise error
+
+ else: # classification
+ if raw_datasets["train"].features["label"].dtype == "list": # multi-label classification
+ is_multi_label = True
+ logger.info("Label type is list, doing multi-label classification")
+ # Trying to find the number of labels in a multi-label classification task
+ # We have to deal with common cases that labels appear in the training set but not in the validation/test set.
+ # So we build the label list from the union of labels in train/val/test.
+ label_list = get_label_list(raw_datasets, split="train")
+ for split in ["validation", "test"]:
+ if split in raw_datasets:
+ val_or_test_labels = get_label_list(raw_datasets, split=split)
+ diff = set(val_or_test_labels).difference(set(label_list))
+ if len(diff) > 0:
+ # add the labels that appear in val/test but not in train, throw a warning
+ logger.warning(
+ f"Labels {diff} in {split} set but not in training set, adding them to the label list"
+ )
+ label_list += list(diff)
+ # if label is -1, we throw a warning and remove it from the label list
+ for label in label_list:
+ if label == -1:
+ logger.warning("Label -1 found in label list, removing it.")
+ label_list.remove(label)
+
+ label_list.sort()
+ num_labels = len(label_list)
+ if num_labels <= 1:
+ raise ValueError("You need more than one label to do classification.")
+
+ # Load pretrained model and tokenizer
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ num_labels=num_labels,
+ finetuning_task="text-classification",
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ if is_regression:
+ config.problem_type = "regression"
+ logger.info("setting problem type to regression")
+ elif is_multi_label:
+ config.problem_type = "multi_label_classification"
+ logger.info("setting problem type to multi label classification")
+ else:
+ config.problem_type = "single_label_classification"
+ logger.info("setting problem type to single label classification")
+
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ model = AutoModelForSequenceClassification.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ ignore_mismatched_sizes=model_args.ignore_mismatched_sizes,
+ )
+
+ # Padding strategy
+ if data_args.pad_to_max_length:
+ padding = "max_length"
+ else:
+ # We will pad later, dynamically at batch creation, to the max sequence length in each batch
+ padding = False
+
+ # for training ,we will update the config with label infos,
+ # if do_train is not set, we will use the label infos in the config
+ if training_args.do_train and not is_regression: # classification, training
+ label_to_id = {v: i for i, v in enumerate(label_list)}
+ # update config with label infos
+ if model.config.label2id != label_to_id:
+ logger.warning(
+ "The label2id key in the model config.json is not equal to the label2id key of this "
+ "run. You can ignore this if you are doing finetuning."
+ )
+ model.config.label2id = label_to_id
+ model.config.id2label = {id: label for label, id in label_to_id.items()}
+ elif not is_regression: # classification, but not training
+ logger.info("using label infos in the model config")
+ logger.info("label2id: {}".format(model.config.label2id))
+ label_to_id = model.config.label2id
+ else: # regression
+ label_to_id = None
+
+ if data_args.max_seq_length > tokenizer.model_max_length:
+ logger.warning(
+ f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
+ f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
+ )
+ max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
+
+ def multi_labels_to_ids(labels: List[str]) -> List[float]:
+ ids = [0.0] * len(label_to_id) # BCELoss requires float as target type
+ for label in labels:
+ ids[label_to_id[label]] = 1.0
+ return ids
+
+ def preprocess_function(examples):
+ if data_args.text_column_names is not None:
+ text_column_names = data_args.text_column_names.split(",")
+ # join together text columns into "sentence" column
+ examples["sentence"] = examples[text_column_names[0]]
+ for column in text_column_names[1:]:
+ for i in range(len(examples[column])):
+ examples["sentence"][i] += data_args.text_column_delimiter + examples[column][i]
+ # Tokenize the texts
+ result = tokenizer(examples["sentence"], padding=padding, max_length=max_seq_length, truncation=True)
+ if label_to_id is not None and "label" in examples:
+ if is_multi_label:
+ result["label"] = [multi_labels_to_ids(l) for l in examples["label"]]
+ else:
+ result["label"] = [(label_to_id[str(l)] if l != -1 else -1) for l in examples["label"]]
+ return result
+
+ # Running the preprocessing pipeline on all the datasets
+ with training_args.main_process_first(desc="dataset map pre-processing"):
+ raw_datasets = raw_datasets.map(
+ preprocess_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on dataset",
+ )
+
+ if training_args.do_train:
+ if "train" not in raw_datasets:
+ raise ValueError("--do_train requires a train dataset.")
+ train_dataset = raw_datasets["train"]
+ if data_args.shuffle_train_dataset:
+ logger.info("Shuffling the training dataset")
+ train_dataset = train_dataset.shuffle(seed=data_args.shuffle_seed)
+ if data_args.max_train_samples is not None:
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+
+ if training_args.do_eval:
+ if "validation" not in raw_datasets and "validation_matched" not in raw_datasets:
+ if "test" not in raw_datasets and "test_matched" not in raw_datasets:
+ raise ValueError("--do_eval requires a validation or test dataset if validation is not defined.")
+ else:
+ logger.warning("Validation dataset not found. Falling back to test dataset for validation.")
+ eval_dataset = raw_datasets["test"]
+ else:
+ eval_dataset = raw_datasets["validation"]
+
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+
+ if training_args.do_predict or data_args.test_file is not None:
+ if "test" not in raw_datasets:
+ raise ValueError("--do_predict requires a test dataset")
+ predict_dataset = raw_datasets["test"]
+ # remove label column if it exists
+ if data_args.max_predict_samples is not None:
+ max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
+ predict_dataset = predict_dataset.select(range(max_predict_samples))
+
+ # Log a few random samples from the training set:
+ if training_args.do_train:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ if data_args.metric_name is not None:
+ metric = (
+ evaluate.load(data_args.metric_name, config_name="multilabel", cache_dir=model_args.cache_dir)
+ if is_multi_label
+ else evaluate.load(data_args.metric_name, cache_dir=model_args.cache_dir)
+ )
+ logger.info(f"Using metric {data_args.metric_name} for evaluation.")
+ else:
+ if is_regression:
+ metric = evaluate.load("mse", cache_dir=model_args.cache_dir)
+ logger.info("Using mean squared error (mse) as regression score, you can use --metric_name to overwrite.")
+ else:
+ if is_multi_label:
+ metric = evaluate.load("f1", config_name="multilabel", cache_dir=model_args.cache_dir)
+ logger.info(
+ "Using multilabel F1 for multi-label classification task, you can use --metric_name to overwrite."
+ )
+ else:
+ metric = evaluate.load("accuracy", cache_dir=model_args.cache_dir)
+ logger.info("Using accuracy as classification score, you can use --metric_name to overwrite.")
+
+ def compute_metrics(p: EvalPrediction):
+ preds = p.predictions[0] if isinstance(p.predictions, tuple) else p.predictions
+ if is_regression:
+ preds = np.squeeze(preds)
+ result = metric.compute(predictions=preds, references=p.label_ids)
+ elif is_multi_label:
+ preds = np.array([np.where(p > 0, 1, 0) for p in preds]) # convert logits to multi-hot encoding
+ # Micro F1 is commonly used in multi-label classification
+ result = metric.compute(predictions=preds, references=p.label_ids, average="micro")
+ else:
+ preds = np.argmax(preds, axis=1)
+ result = metric.compute(predictions=preds, references=p.label_ids)
+ if len(result) > 1:
+ result["combined_score"] = np.mean(list(result.values())).item()
+ return result
+
+ # Data collator will default to DataCollatorWithPadding when the tokenizer is passed to Trainer, so we change it if
+ # we already did the padding.
+ if data_args.pad_to_max_length:
+ data_collator = default_data_collator
+ elif training_args.fp16:
+ data_collator = DataCollatorWithPadding(tokenizer, pad_to_multiple_of=8)
+ else:
+ data_collator = None
+
+ # Initialize our Trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset if training_args.do_train else None,
+ eval_dataset=eval_dataset if training_args.do_eval else None,
+ compute_metrics=compute_metrics,
+ processing_class=tokenizer,
+ data_collator=data_collator,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ metrics = train_result.metrics
+ max_train_samples = (
+ data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
+ )
+ metrics["train_samples"] = min(max_train_samples, len(train_dataset))
+ trainer.save_model() # Saves the tokenizer too for easy upload
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+ metrics = trainer.evaluate(eval_dataset=eval_dataset)
+ max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
+ metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ if training_args.do_predict:
+ logger.info("*** Predict ***")
+ # Removing the `label` columns if exists because it might contains -1 and Trainer won't like that.
+ if "label" in predict_dataset.features:
+ predict_dataset = predict_dataset.remove_columns("label")
+ predictions = trainer.predict(predict_dataset, metric_key_prefix="predict").predictions
+ if is_regression:
+ predictions = np.squeeze(predictions)
+ elif is_multi_label:
+ # Convert logits to multi-hot encoding. We compare the logits to 0 instead of 0.5, because the sigmoid is not applied.
+ # You can also pass `preprocess_logits_for_metrics=lambda logits, labels: nn.functional.sigmoid(logits)` to the Trainer
+ # and set p > 0.5 below (less efficient in this case)
+ predictions = np.array([np.where(p > 0, 1, 0) for p in predictions])
+ else:
+ predictions = np.argmax(predictions, axis=1)
+ output_predict_file = os.path.join(training_args.output_dir, "predict_results.txt")
+ if trainer.is_world_process_zero():
+ with open(output_predict_file, "w") as writer:
+ logger.info("***** Predict results *****")
+ writer.write("index\tprediction\n")
+ for index, item in enumerate(predictions):
+ if is_regression:
+ writer.write(f"{index}\t{item:3.3f}\n")
+ elif is_multi_label:
+ # recover from multi-hot encoding
+ item = [label_list[i] for i in range(len(item)) if item[i] == 1]
+ writer.write(f"{index}\t{item}\n")
+ else:
+ item = label_list[item]
+ writer.write(f"{index}\t{item}\n")
+ logger.info("Predict results saved at {}".format(output_predict_file))
+ kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "text-classification"}
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/run_glue.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/run_glue.py
new file mode 100644
index 0000000000000000000000000000000000000000..9f1c93f3df2edbbdf3ad7ec40a5a35d7d10c4a64
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/run_glue.py
@@ -0,0 +1,637 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2020 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Finetuning the library models for sequence classification on GLUE."""
+# You can also adapt this script on your own text classification task. Pointers for this are left as comments.
+
+import logging
+import os
+import random
+import sys
+from dataclasses import dataclass, field
+from typing import Optional
+
+import datasets
+import evaluate
+import numpy as np
+from datasets import load_dataset
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForSequenceClassification,
+ AutoTokenizer,
+ DataCollatorWithPadding,
+ EvalPrediction,
+ HfArgumentParser,
+ PretrainedConfig,
+ Trainer,
+ TrainingArguments,
+ default_data_collator,
+ set_seed,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/text-classification/requirements.txt")
+
+task_to_keys = {
+ "cola": ("sentence", None),
+ "mnli": ("premise", "hypothesis"),
+ "mrpc": ("sentence1", "sentence2"),
+ "qnli": ("question", "sentence"),
+ "qqp": ("question1", "question2"),
+ "rte": ("sentence1", "sentence2"),
+ "sst2": ("sentence", None),
+ "stsb": ("sentence1", "sentence2"),
+ "wnli": ("sentence1", "sentence2"),
+}
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+
+ Using `HfArgumentParser` we can turn this class
+ into argparse arguments to be able to specify them on
+ the command line.
+ """
+
+ task_name: Optional[str] = field(
+ default=None,
+ metadata={"help": "The name of the task to train on: " + ", ".join(task_to_keys.keys())},
+ )
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ max_seq_length: int = field(
+ default=128,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached preprocessed datasets or not."}
+ )
+ pad_to_max_length: bool = field(
+ default=True,
+ metadata={
+ "help": (
+ "Whether to pad all samples to `max_seq_length`. "
+ "If False, will pad the samples dynamically when batching to the maximum length in the batch."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_predict_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of prediction examples to this "
+ "value if set."
+ )
+ },
+ )
+ train_file: Optional[str] = field(
+ default=None, metadata={"help": "A csv or a json file containing the training data."}
+ )
+ validation_file: Optional[str] = field(
+ default=None, metadata={"help": "A csv or a json file containing the validation data."}
+ )
+ test_file: Optional[str] = field(default=None, metadata={"help": "A csv or a json file containing the test data."})
+
+ def __post_init__(self):
+ if self.task_name is not None:
+ self.task_name = self.task_name.lower()
+ if self.task_name not in task_to_keys.keys():
+ raise ValueError("Unknown task, you should pick one in " + ",".join(task_to_keys.keys()))
+ elif self.dataset_name is not None:
+ pass
+ elif self.train_file is None or self.validation_file is None:
+ raise ValueError("Need either a GLUE task, a training/validation file or a dataset name.")
+ else:
+ train_extension = self.train_file.split(".")[-1]
+ assert train_extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ validation_extension = self.validation_file.split(".")[-1]
+ assert (
+ validation_extension == train_extension
+ ), "`validation_file` should have the same extension (csv or json) as `train_file`."
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ ignore_mismatched_sizes: bool = field(
+ default=False,
+ metadata={"help": "Will enable to load a pretrained model whose head dimensions are different."},
+ )
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_glue", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ datasets.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Get the datasets: you can either provide your own CSV/JSON training and evaluation files (see below)
+ # or specify a GLUE benchmark task (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use as labels the column called 'label' and as pair of sentences the
+ # sentences in columns called 'sentence1' and 'sentence2' if such column exists or the first two columns not named
+ # label if at least two columns are provided.
+ #
+ # If the CSVs/JSONs contain only one non-label column, the script does single sentence classification on this
+ # single column. You can easily tweak this behavior (see below)
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.task_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ "nyu-mll/glue",
+ data_args.task_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ elif data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ # Loading a dataset from your local files.
+ # CSV/JSON training and evaluation files are needed.
+ data_files = {"train": data_args.train_file, "validation": data_args.validation_file}
+
+ # Get the test dataset: you can provide your own CSV/JSON test file (see below)
+ # when you use `do_predict` without specifying a GLUE benchmark task.
+ if training_args.do_predict:
+ if data_args.test_file is not None:
+ train_extension = data_args.train_file.split(".")[-1]
+ test_extension = data_args.test_file.split(".")[-1]
+ assert (
+ test_extension == train_extension
+ ), "`test_file` should have the same extension (csv or json) as `train_file`."
+ data_files["test"] = data_args.test_file
+ else:
+ raise ValueError("Need either a GLUE task or a test file for `do_predict`.")
+
+ for key in data_files.keys():
+ logger.info(f"load a local file for {key}: {data_files[key]}")
+
+ if data_args.train_file.endswith(".csv"):
+ # Loading a dataset from local csv files
+ raw_datasets = load_dataset(
+ "csv",
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ else:
+ # Loading a dataset from local json files
+ raw_datasets = load_dataset(
+ "json",
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ # See more about loading any type of standard or custom dataset at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Labels
+ if data_args.task_name is not None:
+ is_regression = data_args.task_name == "stsb"
+ if not is_regression:
+ label_list = raw_datasets["train"].features["label"].names
+ num_labels = len(label_list)
+ else:
+ num_labels = 1
+ else:
+ # Trying to have good defaults here, don't hesitate to tweak to your needs.
+ is_regression = raw_datasets["train"].features["label"].dtype in ["float32", "float64"]
+ if is_regression:
+ num_labels = 1
+ else:
+ # A useful fast method:
+ # https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Dataset.unique
+ label_list = raw_datasets["train"].unique("label")
+ label_list.sort() # Let's sort it for determinism
+ num_labels = len(label_list)
+
+ # Load pretrained model and tokenizer
+ #
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ num_labels=num_labels,
+ finetuning_task=data_args.task_name,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ model = AutoModelForSequenceClassification.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ ignore_mismatched_sizes=model_args.ignore_mismatched_sizes,
+ )
+
+ # Preprocessing the raw_datasets
+ if data_args.task_name is not None:
+ sentence1_key, sentence2_key = task_to_keys[data_args.task_name]
+ else:
+ # Again, we try to have some nice defaults but don't hesitate to tweak to your use case.
+ non_label_column_names = [name for name in raw_datasets["train"].column_names if name != "label"]
+ if "sentence1" in non_label_column_names and "sentence2" in non_label_column_names:
+ sentence1_key, sentence2_key = "sentence1", "sentence2"
+ else:
+ if len(non_label_column_names) >= 2:
+ sentence1_key, sentence2_key = non_label_column_names[:2]
+ else:
+ sentence1_key, sentence2_key = non_label_column_names[0], None
+
+ # Padding strategy
+ if data_args.pad_to_max_length:
+ padding = "max_length"
+ else:
+ # We will pad later, dynamically at batch creation, to the max sequence length in each batch
+ padding = False
+
+ # Some models have set the order of the labels to use, so let's make sure we do use it.
+ label_to_id = None
+ if (
+ model.config.label2id != PretrainedConfig(num_labels=num_labels).label2id
+ and data_args.task_name is not None
+ and not is_regression
+ ):
+ # Some have all caps in their config, some don't.
+ label_name_to_id = {k.lower(): v for k, v in model.config.label2id.items()}
+ if sorted(label_name_to_id.keys()) == sorted(label_list):
+ label_to_id = {i: int(label_name_to_id[label_list[i]]) for i in range(num_labels)}
+ else:
+ logger.warning(
+ "Your model seems to have been trained with labels, but they don't match the dataset: "
+ f"model labels: {sorted(label_name_to_id.keys())}, dataset labels: {sorted(label_list)}."
+ "\nIgnoring the model labels as a result.",
+ )
+ elif data_args.task_name is None and not is_regression:
+ label_to_id = {v: i for i, v in enumerate(label_list)}
+
+ if label_to_id is not None:
+ model.config.label2id = label_to_id
+ model.config.id2label = {id: label for label, id in config.label2id.items()}
+ elif data_args.task_name is not None and not is_regression:
+ model.config.label2id = {l: i for i, l in enumerate(label_list)}
+ model.config.id2label = {id: label for label, id in config.label2id.items()}
+
+ if data_args.max_seq_length > tokenizer.model_max_length:
+ logger.warning(
+ f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
+ f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
+ )
+ max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
+
+ def preprocess_function(examples):
+ # Tokenize the texts
+ args = (
+ (examples[sentence1_key],) if sentence2_key is None else (examples[sentence1_key], examples[sentence2_key])
+ )
+ result = tokenizer(*args, padding=padding, max_length=max_seq_length, truncation=True)
+
+ # Map labels to IDs (not necessary for GLUE tasks)
+ if label_to_id is not None and "label" in examples:
+ result["label"] = [(label_to_id[l] if l != -1 else -1) for l in examples["label"]]
+ return result
+
+ with training_args.main_process_first(desc="dataset map pre-processing"):
+ raw_datasets = raw_datasets.map(
+ preprocess_function,
+ batched=True,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on dataset",
+ )
+ if training_args.do_train:
+ if "train" not in raw_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = raw_datasets["train"]
+ if data_args.max_train_samples is not None:
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+
+ if training_args.do_eval:
+ if "validation" not in raw_datasets and "validation_matched" not in raw_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_dataset = raw_datasets["validation_matched" if data_args.task_name == "mnli" else "validation"]
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+
+ if training_args.do_predict or data_args.task_name is not None or data_args.test_file is not None:
+ if "test" not in raw_datasets and "test_matched" not in raw_datasets:
+ raise ValueError("--do_predict requires a test dataset")
+ predict_dataset = raw_datasets["test_matched" if data_args.task_name == "mnli" else "test"]
+ if data_args.max_predict_samples is not None:
+ max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
+ predict_dataset = predict_dataset.select(range(max_predict_samples))
+
+ # Log a few random samples from the training set:
+ if training_args.do_train:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ # Get the metric function
+ if data_args.task_name is not None:
+ metric = evaluate.load("glue", data_args.task_name, cache_dir=model_args.cache_dir)
+ elif is_regression:
+ metric = evaluate.load("mse", cache_dir=model_args.cache_dir)
+ else:
+ metric = evaluate.load("accuracy", cache_dir=model_args.cache_dir)
+
+ # You can define your custom compute_metrics function. It takes an `EvalPrediction` object (a namedtuple with a
+ # predictions and label_ids field) and has to return a dictionary string to float.
+ def compute_metrics(p: EvalPrediction):
+ preds = p.predictions[0] if isinstance(p.predictions, tuple) else p.predictions
+ preds = np.squeeze(preds) if is_regression else np.argmax(preds, axis=1)
+ result = metric.compute(predictions=preds, references=p.label_ids)
+ if len(result) > 1:
+ result["combined_score"] = np.mean(list(result.values())).item()
+ return result
+
+ # Data collator will default to DataCollatorWithPadding when the tokenizer is passed to Trainer, so we change it if
+ # we already did the padding.
+ if data_args.pad_to_max_length:
+ data_collator = default_data_collator
+ elif training_args.fp16:
+ data_collator = DataCollatorWithPadding(tokenizer, pad_to_multiple_of=8)
+ else:
+ data_collator = None
+
+ # Initialize our Trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset if training_args.do_train else None,
+ eval_dataset=eval_dataset if training_args.do_eval else None,
+ compute_metrics=compute_metrics,
+ processing_class=tokenizer,
+ data_collator=data_collator,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ metrics = train_result.metrics
+ max_train_samples = (
+ data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
+ )
+ metrics["train_samples"] = min(max_train_samples, len(train_dataset))
+
+ trainer.save_model() # Saves the tokenizer too for easy upload
+
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+
+ # Loop to handle MNLI double evaluation (matched, mis-matched)
+ tasks = [data_args.task_name]
+ eval_datasets = [eval_dataset]
+ if data_args.task_name == "mnli":
+ tasks.append("mnli-mm")
+ valid_mm_dataset = raw_datasets["validation_mismatched"]
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(valid_mm_dataset), data_args.max_eval_samples)
+ valid_mm_dataset = valid_mm_dataset.select(range(max_eval_samples))
+ eval_datasets.append(valid_mm_dataset)
+ combined = {}
+
+ for eval_dataset, task in zip(eval_datasets, tasks):
+ metrics = trainer.evaluate(eval_dataset=eval_dataset)
+
+ max_eval_samples = (
+ data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
+ )
+ metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
+
+ if task == "mnli-mm":
+ metrics = {k + "_mm": v for k, v in metrics.items()}
+ if task is not None and "mnli" in task:
+ combined.update(metrics)
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", combined if task is not None and "mnli" in task else metrics)
+
+ if training_args.do_predict:
+ logger.info("*** Predict ***")
+
+ # Loop to handle MNLI double evaluation (matched, mis-matched)
+ tasks = [data_args.task_name]
+ predict_datasets = [predict_dataset]
+ if data_args.task_name == "mnli":
+ tasks.append("mnli-mm")
+ predict_datasets.append(raw_datasets["test_mismatched"])
+
+ for predict_dataset, task in zip(predict_datasets, tasks):
+ # Removing the `label` columns because it contains -1 and Trainer won't like that.
+ predict_dataset = predict_dataset.remove_columns("label")
+ predictions = trainer.predict(predict_dataset, metric_key_prefix="predict").predictions
+ predictions = np.squeeze(predictions) if is_regression else np.argmax(predictions, axis=1)
+
+ output_predict_file = os.path.join(training_args.output_dir, f"predict_results_{task}.txt")
+ if trainer.is_world_process_zero():
+ with open(output_predict_file, "w") as writer:
+ logger.info(f"***** Predict results {task} *****")
+ writer.write("index\tprediction\n")
+ for index, item in enumerate(predictions):
+ if is_regression:
+ writer.write(f"{index}\t{item:3.3f}\n")
+ else:
+ item = label_list[item]
+ writer.write(f"{index}\t{item}\n")
+
+ kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "text-classification"}
+ if data_args.task_name is not None:
+ kwargs["language"] = "en"
+ kwargs["dataset_tags"] = "glue"
+ kwargs["dataset_args"] = data_args.task_name
+ kwargs["dataset"] = f"GLUE {data_args.task_name.upper()}"
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/run_glue_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/run_glue_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..61bd746f0782e4575caf46053033ddb95310355c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/run_glue_no_trainer.py
@@ -0,0 +1,685 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Finetuning a 🤗 Transformers model for sequence classification on GLUE."""
+
+import argparse
+import json
+import logging
+import math
+import os
+import random
+from pathlib import Path
+
+import datasets
+import evaluate
+import torch
+from accelerate import Accelerator
+from accelerate.logging import get_logger
+from accelerate.utils import set_seed
+from datasets import load_dataset
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from tqdm.auto import tqdm
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForSequenceClassification,
+ AutoTokenizer,
+ DataCollatorWithPadding,
+ PretrainedConfig,
+ SchedulerType,
+ default_data_collator,
+ get_scheduler,
+)
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+logger = get_logger(__name__)
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/text-classification/requirements.txt")
+
+task_to_keys = {
+ "cola": ("sentence", None),
+ "mnli": ("premise", "hypothesis"),
+ "mrpc": ("sentence1", "sentence2"),
+ "qnli": ("question", "sentence"),
+ "qqp": ("question1", "question2"),
+ "rte": ("sentence1", "sentence2"),
+ "sst2": ("sentence", None),
+ "stsb": ("sentence1", "sentence2"),
+ "wnli": ("sentence1", "sentence2"),
+}
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Finetune a transformers model on a text classification task")
+ parser.add_argument(
+ "--task_name",
+ type=str,
+ default=None,
+ help="The name of the glue task to train on.",
+ choices=list(task_to_keys.keys()),
+ )
+ parser.add_argument(
+ "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
+ )
+ parser.add_argument(
+ "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
+ )
+ parser.add_argument(
+ "--max_length",
+ type=int,
+ default=128,
+ help=(
+ "The maximum total input sequence length after tokenization. Sequences longer than this will be truncated,"
+ " sequences shorter will be padded if `--pad_to_max_length` is passed."
+ ),
+ )
+ parser.add_argument(
+ "--pad_to_max_length",
+ action="store_true",
+ help="If passed, pad all samples to `max_length`. Otherwise, dynamic padding is used.",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=True,
+ )
+ parser.add_argument(
+ "--use_slow_tokenizer",
+ action="store_true",
+ help="If passed, will use a slow tokenizer (not backed by the 🤗 Tokenizers library).",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--trust_remote_code",
+ type=bool,
+ default=False,
+ help=(
+ "Whether or not to allow for custom models defined on the Hub in their own modeling files. This option "
+ "should only be set to `True` for repositories you trust and in which you have read the code, as it will "
+ "execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ parser.add_argument(
+ "--ignore_mismatched_sizes",
+ action="store_true",
+ help="Whether or not to enable to load a pretrained model whose head dimensions are different.",
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+ if args.task_name is None and args.train_file is None and args.validation_file is None:
+ raise ValueError("Need either a task name or a training/validation file.")
+ else:
+ if args.train_file is not None:
+ extension = args.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if args.validation_file is not None:
+ extension = args.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+
+ if args.push_to_hub:
+ assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
+
+ return args
+
+
+def main():
+ args = parse_args()
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_glue_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+ accelerator = (
+ Accelerator(log_with=args.report_to, project_dir=args.output_dir) if args.with_tracking else Accelerator()
+ )
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Get the datasets: you can either provide your own CSV/JSON training and evaluation files (see below)
+ # or specify a GLUE benchmark task (the dataset will be downloaded automatically from the datasets Hub).
+
+ # For CSV/JSON files, this script will use as labels the column called 'label' and as pair of sentences the
+ # sentences in columns called 'sentence1' and 'sentence2' if such column exists or the first two columns not named
+ # label if at least two columns are provided.
+
+ # If the CSVs/JSONs contain only one non-label column, the script does single sentence classification on this
+ # single column. You can easily tweak this behavior (see below)
+
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if args.task_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset("nyu-mll/glue", args.task_name)
+ else:
+ # Loading the dataset from local csv or json file.
+ data_files = {}
+ if args.train_file is not None:
+ data_files["train"] = args.train_file
+ if args.validation_file is not None:
+ data_files["validation"] = args.validation_file
+ extension = (args.train_file if args.train_file is not None else args.validation_file).split(".")[-1]
+ raw_datasets = load_dataset(extension, data_files=data_files)
+ # See more about loading any type of standard or custom dataset at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Labels
+ if args.task_name is not None:
+ is_regression = args.task_name == "stsb"
+ if not is_regression:
+ label_list = raw_datasets["train"].features["label"].names
+ num_labels = len(label_list)
+ else:
+ num_labels = 1
+ else:
+ # Trying to have good defaults here, don't hesitate to tweak to your needs.
+ is_regression = raw_datasets["train"].features["label"].dtype in ["float32", "float64"]
+ if is_regression:
+ num_labels = 1
+ else:
+ # A useful fast method:
+ # https://huggingface.co/docs/datasets/package_reference/main_classes.html#datasets.Dataset.unique
+ label_list = raw_datasets["train"].unique("label")
+ label_list.sort() # Let's sort it for determinism
+ num_labels = len(label_list)
+
+ # Load pretrained model and tokenizer
+ #
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config = AutoConfig.from_pretrained(
+ args.model_name_or_path,
+ num_labels=num_labels,
+ finetuning_task=args.task_name,
+ trust_remote_code=args.trust_remote_code,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.model_name_or_path, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
+ )
+ if tokenizer.pad_token is None:
+ tokenizer.pad_token = tokenizer.eos_token
+ config.pad_token_id = tokenizer.pad_token_id
+ model = AutoModelForSequenceClassification.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ ignore_mismatched_sizes=args.ignore_mismatched_sizes,
+ trust_remote_code=args.trust_remote_code,
+ )
+
+ # Preprocessing the datasets
+ if args.task_name is not None:
+ sentence1_key, sentence2_key = task_to_keys[args.task_name]
+ else:
+ # Again, we try to have some nice defaults but don't hesitate to tweak to your use case.
+ non_label_column_names = [name for name in raw_datasets["train"].column_names if name != "label"]
+ if "sentence1" in non_label_column_names and "sentence2" in non_label_column_names:
+ sentence1_key, sentence2_key = "sentence1", "sentence2"
+ else:
+ if len(non_label_column_names) >= 2:
+ sentence1_key, sentence2_key = non_label_column_names[:2]
+ else:
+ sentence1_key, sentence2_key = non_label_column_names[0], None
+
+ # Some models have set the order of the labels to use, so let's make sure we do use it.
+ label_to_id = None
+ if (
+ model.config.label2id != PretrainedConfig(num_labels=num_labels).label2id
+ and args.task_name is not None
+ and not is_regression
+ ):
+ # Some have all caps in their config, some don't.
+ label_name_to_id = {k.lower(): v for k, v in model.config.label2id.items()}
+ if sorted(label_name_to_id.keys()) == sorted(label_list):
+ logger.info(
+ f"The configuration of the model provided the following label correspondence: {label_name_to_id}. "
+ "Using it!"
+ )
+ label_to_id = {i: label_name_to_id[label_list[i]] for i in range(num_labels)}
+ else:
+ logger.warning(
+ "Your model seems to have been trained with labels, but they don't match the dataset: "
+ f"model labels: {sorted(label_name_to_id.keys())}, dataset labels: {sorted(label_list)}."
+ "\nIgnoring the model labels as a result.",
+ )
+ elif args.task_name is None and not is_regression:
+ label_to_id = {v: i for i, v in enumerate(label_list)}
+
+ if label_to_id is not None:
+ model.config.label2id = label_to_id
+ model.config.id2label = {id: label for label, id in config.label2id.items()}
+ elif args.task_name is not None and not is_regression:
+ model.config.label2id = {l: i for i, l in enumerate(label_list)}
+ model.config.id2label = {id: label for label, id in config.label2id.items()}
+
+ padding = "max_length" if args.pad_to_max_length else False
+
+ def preprocess_function(examples):
+ # Tokenize the texts
+ texts = (
+ (examples[sentence1_key],) if sentence2_key is None else (examples[sentence1_key], examples[sentence2_key])
+ )
+ result = tokenizer(*texts, padding=padding, max_length=args.max_length, truncation=True)
+
+ if "label" in examples:
+ if label_to_id is not None:
+ # Map labels to IDs (not necessary for GLUE tasks)
+ result["labels"] = [label_to_id[l] for l in examples["label"]]
+ else:
+ # In all cases, rename the column to labels because the model will expect that.
+ result["labels"] = examples["label"]
+ return result
+
+ with accelerator.main_process_first():
+ processed_datasets = raw_datasets.map(
+ preprocess_function,
+ batched=True,
+ remove_columns=raw_datasets["train"].column_names,
+ desc="Running tokenizer on dataset",
+ )
+
+ train_dataset = processed_datasets["train"]
+ eval_dataset = processed_datasets["validation_matched" if args.task_name == "mnli" else "validation"]
+
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ # DataLoaders creation:
+ if args.pad_to_max_length:
+ # If padding was already done ot max length, we use the default data collator that will just convert everything
+ # to tensors.
+ data_collator = default_data_collator
+ else:
+ # Otherwise, `DataCollatorWithPadding` will apply dynamic padding for us (by padding to the maximum length of
+ # the samples passed). When using mixed precision, we add `pad_to_multiple_of=8` to pad all tensors to multiple
+ # of 8s, which will enable the use of Tensor Cores on NVIDIA hardware with compute capability >= 7.5 (Volta).
+ # For fp8, we pad to multiple of 16.
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+ data_collator = DataCollatorWithPadding(tokenizer, pad_to_multiple_of=pad_to_multiple_of)
+
+ train_dataloader = DataLoader(
+ train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
+ )
+ eval_dataloader = DataLoader(eval_dataset, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size)
+
+ # Optimizer
+ # Split weights in two groups, one with weight decay and the other not.
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps,
+ num_training_steps=args.max_train_steps,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("glue_no_trainer", experiment_config)
+
+ # Get the metric function
+ if args.task_name is not None:
+ metric = evaluate.load("glue", args.task_name)
+ else:
+ metric = evaluate.load("accuracy")
+
+ # Train!
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ checkpoint_path = args.resume_from_checkpoint
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ checkpoint_path = path
+ path = os.path.basename(checkpoint_path)
+
+ accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
+ accelerator.load_state(checkpoint_path)
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ completed_steps = resume_step // args.gradient_accumulation_steps
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We skip the first `n` batches in the dataloader when resuming from a checkpoint
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ loss = loss / args.gradient_accumulation_steps
+ accelerator.backward(loss)
+ if step % args.gradient_accumulation_steps == 0 or step == len(train_dataloader) - 1:
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if completed_steps >= args.max_train_steps:
+ break
+
+ model.eval()
+ samples_seen = 0
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1) if not is_regression else outputs.logits.squeeze()
+ predictions, references = accelerator.gather((predictions, batch["labels"]))
+ # If we are in a multiprocess environment, the last batch has duplicates
+ if accelerator.num_processes > 1:
+ if step == len(eval_dataloader) - 1:
+ predictions = predictions[: len(eval_dataloader.dataset) - samples_seen]
+ references = references[: len(eval_dataloader.dataset) - samples_seen]
+ else:
+ samples_seen += references.shape[0]
+ metric.add_batch(
+ predictions=predictions,
+ references=references,
+ )
+
+ eval_metric = metric.compute()
+ logger.info(f"epoch {epoch}: {eval_metric}")
+
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "accuracy" if args.task_name is not None else "glue": eval_metric,
+ "train_loss": total_loss.item() / len(train_dataloader),
+ "epoch": epoch,
+ "step": completed_steps,
+ },
+ step=completed_steps,
+ )
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if args.checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.with_tracking:
+ accelerator.end_training()
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ if args.push_to_hub:
+ api.upload_folder(
+ commit_message="End of training",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if args.task_name == "mnli":
+ # Final evaluation on mismatched validation set
+ eval_dataset = processed_datasets["validation_mismatched"]
+ eval_dataloader = DataLoader(
+ eval_dataset, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size
+ )
+ eval_dataloader = accelerator.prepare(eval_dataloader)
+
+ model.eval()
+ for step, batch in enumerate(eval_dataloader):
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ metric.add_batch(
+ predictions=accelerator.gather(predictions),
+ references=accelerator.gather(batch["labels"]),
+ )
+
+ eval_metric = metric.compute()
+ logger.info(f"mnli-mm: {eval_metric}")
+
+ if args.output_dir is not None:
+ all_results = {f"eval_{k}": v for k, v in eval_metric.items()}
+ with open(os.path.join(args.output_dir, "all_results.json"), "w") as f:
+ json.dump(all_results, f)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/run_xnli.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/run_xnli.py
new file mode 100644
index 0000000000000000000000000000000000000000..0c7d2c44b8788e8b84704580d5d4803dff4f2ed2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-classification/run_xnli.py
@@ -0,0 +1,455 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Finetuning multi-lingual models on XNLI (e.g. Bert, DistilBERT, XLM).
+Adapted from `examples/text-classification/run_glue.py`"""
+
+import logging
+import os
+import random
+import sys
+from dataclasses import dataclass, field
+from typing import Optional
+
+import datasets
+import evaluate
+import numpy as np
+from datasets import load_dataset
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForSequenceClassification,
+ AutoTokenizer,
+ DataCollatorWithPadding,
+ EvalPrediction,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ default_data_collator,
+ set_seed,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/text-classification/requirements.txt")
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+
+ Using `HfArgumentParser` we can turn this class
+ into argparse arguments to be able to specify them on
+ the command line.
+ """
+
+ max_seq_length: Optional[int] = field(
+ default=128,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached preprocessed datasets or not."}
+ )
+ pad_to_max_length: bool = field(
+ default=True,
+ metadata={
+ "help": (
+ "Whether to pad all samples to `max_seq_length`. "
+ "If False, will pad the samples dynamically when batching to the maximum length in the batch."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_predict_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of prediction examples to this "
+ "value if set."
+ )
+ },
+ )
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ default=None, metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ language: str = field(
+ default=None, metadata={"help": "Evaluation language. Also train language if `train_language` is set to None."}
+ )
+ train_language: Optional[str] = field(
+ default=None, metadata={"help": "Train language if it is different from the evaluation language."}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+ do_lower_case: Optional[bool] = field(
+ default=False,
+ metadata={"help": "arg to indicate if tokenizer should do lower case in AutoTokenizer.from_pretrained()"},
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether or not to allow for custom models defined on the Hub in their own modeling files. This option "
+ "should only be set to `True` for repositories you trust and in which you have read the code, as it will "
+ "execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ ignore_mismatched_sizes: bool = field(
+ default=False,
+ metadata={"help": "Will enable to load a pretrained model whose head dimensions are different."},
+ )
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_xnli", model_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ datasets.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # In distributed training, the load_dataset function guarantees that only one local process can concurrently
+ # download the dataset.
+ # Downloading and loading xnli dataset from the hub.
+ if training_args.do_train:
+ if model_args.train_language is None:
+ train_dataset = load_dataset(
+ "xnli",
+ model_args.language,
+ split="train",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ else:
+ train_dataset = load_dataset(
+ "xnli",
+ model_args.train_language,
+ split="train",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ label_list = train_dataset.features["label"].names
+
+ if training_args.do_eval:
+ eval_dataset = load_dataset(
+ "xnli",
+ model_args.language,
+ split="validation",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ label_list = eval_dataset.features["label"].names
+
+ if training_args.do_predict:
+ predict_dataset = load_dataset(
+ "xnli",
+ model_args.language,
+ split="test",
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ label_list = predict_dataset.features["label"].names
+
+ # Labels
+ num_labels = len(label_list)
+
+ # Load pretrained model and tokenizer
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ num_labels=num_labels,
+ id2label={str(i): label for i, label in enumerate(label_list)},
+ label2id={label: i for i, label in enumerate(label_list)},
+ finetuning_task="xnli",
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ do_lower_case=model_args.do_lower_case,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ model = AutoModelForSequenceClassification.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ ignore_mismatched_sizes=model_args.ignore_mismatched_sizes,
+ )
+
+ # Preprocessing the datasets
+ # Padding strategy
+ if data_args.pad_to_max_length:
+ padding = "max_length"
+ else:
+ # We will pad later, dynamically at batch creation, to the max sequence length in each batch
+ padding = False
+
+ def preprocess_function(examples):
+ # Tokenize the texts
+ return tokenizer(
+ examples["premise"],
+ examples["hypothesis"],
+ padding=padding,
+ max_length=data_args.max_seq_length,
+ truncation=True,
+ )
+
+ if training_args.do_train:
+ if data_args.max_train_samples is not None:
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+ with training_args.main_process_first(desc="train dataset map pre-processing"):
+ train_dataset = train_dataset.map(
+ preprocess_function,
+ batched=True,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on train dataset",
+ )
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ if training_args.do_eval:
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+ with training_args.main_process_first(desc="validation dataset map pre-processing"):
+ eval_dataset = eval_dataset.map(
+ preprocess_function,
+ batched=True,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on validation dataset",
+ )
+
+ if training_args.do_predict:
+ if data_args.max_predict_samples is not None:
+ max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
+ predict_dataset = predict_dataset.select(range(max_predict_samples))
+ with training_args.main_process_first(desc="prediction dataset map pre-processing"):
+ predict_dataset = predict_dataset.map(
+ preprocess_function,
+ batched=True,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on prediction dataset",
+ )
+
+ # Get the metric function
+ metric = evaluate.load("xnli", cache_dir=model_args.cache_dir)
+
+ # You can define your custom compute_metrics function. It takes an `EvalPrediction` object (a namedtuple with a
+ # predictions and label_ids field) and has to return a dictionary string to float.
+ def compute_metrics(p: EvalPrediction):
+ preds = p.predictions[0] if isinstance(p.predictions, tuple) else p.predictions
+ preds = np.argmax(preds, axis=1)
+ return metric.compute(predictions=preds, references=p.label_ids)
+
+ # Data collator will default to DataCollatorWithPadding, so we change it if we already did the padding.
+ if data_args.pad_to_max_length:
+ data_collator = default_data_collator
+ elif training_args.fp16:
+ data_collator = DataCollatorWithPadding(tokenizer, pad_to_multiple_of=8)
+ else:
+ data_collator = None
+
+ # Initialize our Trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset if training_args.do_train else None,
+ eval_dataset=eval_dataset if training_args.do_eval else None,
+ compute_metrics=compute_metrics,
+ processing_class=tokenizer,
+ data_collator=data_collator,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ metrics = train_result.metrics
+ max_train_samples = (
+ data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
+ )
+ metrics["train_samples"] = min(max_train_samples, len(train_dataset))
+
+ trainer.save_model() # Saves the tokenizer too for easy upload
+
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+ metrics = trainer.evaluate(eval_dataset=eval_dataset)
+
+ max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
+ metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ # Prediction
+ if training_args.do_predict:
+ logger.info("*** Predict ***")
+ predictions, labels, metrics = trainer.predict(predict_dataset, metric_key_prefix="predict")
+
+ max_predict_samples = (
+ data_args.max_predict_samples if data_args.max_predict_samples is not None else len(predict_dataset)
+ )
+ metrics["predict_samples"] = min(max_predict_samples, len(predict_dataset))
+
+ trainer.log_metrics("predict", metrics)
+ trainer.save_metrics("predict", metrics)
+
+ predictions = np.argmax(predictions, axis=1)
+ output_predict_file = os.path.join(training_args.output_dir, "predictions.txt")
+ if trainer.is_world_process_zero():
+ with open(output_predict_file, "w") as writer:
+ writer.write("index\tprediction\n")
+ for index, item in enumerate(predictions):
+ item = label_list[item]
+ writer.write(f"{index}\t{item}\n")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-generation/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-generation/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..72fc25e13c65e7a55f459d036a584143520a0696
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-generation/README.md
@@ -0,0 +1,31 @@
+
+
+## Language generation
+
+Based on the script [`run_generation.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-generation/run_generation.py).
+
+Conditional text generation using the auto-regressive models of the library: GPT, GPT-2, GPT-J, Transformer-XL, XLNet, CTRL, BLOOM, LLAMA, OPT.
+A similar script is used for our official demo [Write With Transfomer](https://transformer.huggingface.co), where you
+can try out the different models available in the library.
+
+Example usage:
+
+```bash
+python run_generation.py \
+ --model_type=gpt2 \
+ --model_name_or_path=openai-community/gpt2
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-generation/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-generation/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..324a8cfb1c29e01bcaccae84e8c5a566f2d5dfbb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-generation/requirements.txt
@@ -0,0 +1,4 @@
+accelerate >= 0.21.0
+sentencepiece != 0.1.92
+protobuf
+torch >= 1.3
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-generation/run_generation.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-generation/run_generation.py
new file mode 100644
index 0000000000000000000000000000000000000000..0e21a242684d35408bafb4086ac53470a8e45270
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-generation/run_generation.py
@@ -0,0 +1,447 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2018 Google AI, Google Brain and Carnegie Mellon University Authors and the HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Conditional text generation with the auto-regressive models of the library (GPT/GPT-2/CTRL/Transformer-XL/XLNet)"""
+
+import argparse
+import inspect
+import logging
+from typing import Tuple
+
+import torch
+from accelerate import PartialState
+from accelerate.utils import set_seed
+
+from transformers import (
+ AutoTokenizer,
+ BloomForCausalLM,
+ BloomTokenizerFast,
+ CTRLLMHeadModel,
+ CTRLTokenizer,
+ GenerationMixin,
+ GPT2LMHeadModel,
+ GPT2Tokenizer,
+ GPTJForCausalLM,
+ LlamaForCausalLM,
+ LlamaTokenizer,
+ OpenAIGPTLMHeadModel,
+ OpenAIGPTTokenizer,
+ OPTForCausalLM,
+ TransfoXLLMHeadModel,
+ TransfoXLTokenizer,
+ XLMTokenizer,
+ XLMWithLMHeadModel,
+ XLNetLMHeadModel,
+ XLNetTokenizer,
+)
+from transformers.modeling_outputs import CausalLMOutputWithPast
+
+
+logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+)
+logger = logging.getLogger(__name__)
+
+MAX_LENGTH = int(10000) # Hardcoded max length to avoid infinite loop
+
+MODEL_CLASSES = {
+ "gpt2": (GPT2LMHeadModel, GPT2Tokenizer),
+ "ctrl": (CTRLLMHeadModel, CTRLTokenizer),
+ "openai-gpt": (OpenAIGPTLMHeadModel, OpenAIGPTTokenizer),
+ "xlnet": (XLNetLMHeadModel, XLNetTokenizer),
+ "transfo-xl": (TransfoXLLMHeadModel, TransfoXLTokenizer),
+ "xlm": (XLMWithLMHeadModel, XLMTokenizer),
+ "gptj": (GPTJForCausalLM, AutoTokenizer),
+ "bloom": (BloomForCausalLM, BloomTokenizerFast),
+ "llama": (LlamaForCausalLM, LlamaTokenizer),
+ "opt": (OPTForCausalLM, GPT2Tokenizer),
+}
+
+# Padding text to help Transformer-XL and XLNet with short prompts as proposed by Aman Rusia
+# in https://github.com/rusiaaman/XLNet-gen#methodology
+# and https://medium.com/@amanrusia/xlnet-speaks-comparison-to-gpt-2-ea1a4e9ba39e
+PREFIX = """In 1991, the remains of Russian Tsar Nicholas II and his family
+(except for Alexei and Maria) are discovered.
+The voice of Nicholas's young son, Tsarevich Alexei Nikolaevich, narrates the
+remainder of the story. 1883 Western Siberia,
+a young Grigori Rasputin is asked by his father and a group of men to perform magic.
+Rasputin has a vision and denounces one of the men as a horse thief. Although his
+father initially slaps him for making such an accusation, Rasputin watches as the
+man is chased outside and beaten. Twenty years later, Rasputin sees a vision of
+the Virgin Mary, prompting him to become a priest. Rasputin quickly becomes famous,
+with people, even a bishop, begging for his blessing. """
+
+
+#
+# Functions to prepare models' input
+#
+
+
+def prepare_ctrl_input(args, _, tokenizer, prompt_text):
+ if args.temperature > 0.7:
+ logger.info("CTRL typically works better with lower temperatures (and lower top_k).")
+
+ encoded_prompt = tokenizer.encode(prompt_text, add_special_tokens=False)
+ if not any(encoded_prompt[0] == x for x in tokenizer.control_codes.values()):
+ logger.info("WARNING! You are not starting your generation from a control code so you won't get good results")
+ return prompt_text
+
+
+def prepare_xlm_input(args, model, tokenizer, prompt_text):
+ # kwargs = {"language": None, "mask_token_id": None}
+
+ # Set the language
+ use_lang_emb = hasattr(model.config, "use_lang_emb") and model.config.use_lang_emb
+ if hasattr(model.config, "lang2id") and use_lang_emb:
+ available_languages = model.config.lang2id.keys()
+ if args.xlm_language in available_languages:
+ language = args.xlm_language
+ else:
+ language = None
+ while language not in available_languages:
+ language = input("Using XLM. Select language in " + str(list(available_languages)) + " >>> ")
+
+ model.config.lang_id = model.config.lang2id[language]
+ # kwargs["language"] = tokenizer.lang2id[language]
+
+ # TODO fix mask_token_id setup when configurations will be synchronized between models and tokenizers
+ # XLM masked-language modeling (MLM) models need masked token
+ # is_xlm_mlm = "mlm" in args.model_name_or_path
+ # if is_xlm_mlm:
+ # kwargs["mask_token_id"] = tokenizer.mask_token_id
+
+ return prompt_text
+
+
+def prepare_xlnet_input(args, _, tokenizer, prompt_text):
+ prefix = args.prefix if args.prefix else args.padding_text if args.padding_text else PREFIX
+ prompt_text = prefix + prompt_text
+ return prompt_text
+
+
+def prepare_transfoxl_input(args, _, tokenizer, prompt_text):
+ prefix = args.prefix if args.prefix else args.padding_text if args.padding_text else PREFIX
+ prompt_text = prefix + prompt_text
+ return prompt_text
+
+
+PREPROCESSING_FUNCTIONS = {
+ "ctrl": prepare_ctrl_input,
+ "xlm": prepare_xlm_input,
+ "xlnet": prepare_xlnet_input,
+ "transfo-xl": prepare_transfoxl_input,
+}
+
+
+def adjust_length_to_model(length, max_sequence_length):
+ if length < 0 and max_sequence_length > 0:
+ length = max_sequence_length
+ elif 0 < max_sequence_length < length:
+ length = max_sequence_length # No generation bigger than model size
+ elif length < 0:
+ length = MAX_LENGTH # avoid infinite loop
+ return length
+
+
+def sparse_model_config(model_config):
+ embedding_size = None
+ if hasattr(model_config, "hidden_size"):
+ embedding_size = model_config.hidden_size
+ elif hasattr(model_config, "n_embed"):
+ embedding_size = model_config.n_embed
+ elif hasattr(model_config, "n_embd"):
+ embedding_size = model_config.n_embd
+
+ num_head = None
+ if hasattr(model_config, "num_attention_heads"):
+ num_head = model_config.num_attention_heads
+ elif hasattr(model_config, "n_head"):
+ num_head = model_config.n_head
+
+ if embedding_size is None or num_head is None or num_head == 0:
+ raise ValueError("Check the model config")
+
+ num_embedding_size_per_head = int(embedding_size / num_head)
+ if hasattr(model_config, "n_layer"):
+ num_layer = model_config.n_layer
+ elif hasattr(model_config, "num_hidden_layers"):
+ num_layer = model_config.num_hidden_layers
+ else:
+ raise ValueError("Number of hidden layers couldn't be determined from the model config")
+
+ return num_layer, num_head, num_embedding_size_per_head
+
+
+def generate_past_key_values(model, batch_size, seq_len):
+ num_block_layers, num_attention_heads, num_embedding_size_per_head = sparse_model_config(model.config)
+ if model.config.model_type == "bloom":
+ past_key_values = tuple(
+ (
+ torch.empty(int(num_attention_heads * batch_size), num_embedding_size_per_head, seq_len)
+ .to(model.dtype)
+ .to(model.device),
+ torch.empty(int(num_attention_heads * batch_size), seq_len, num_embedding_size_per_head)
+ .to(model.dtype)
+ .to(model.device),
+ )
+ for _ in range(num_block_layers)
+ )
+ else:
+ past_key_values = tuple(
+ (
+ torch.empty(batch_size, num_attention_heads, seq_len, num_embedding_size_per_head)
+ .to(model.dtype)
+ .to(model.device),
+ torch.empty(batch_size, num_attention_heads, seq_len, num_embedding_size_per_head)
+ .to(model.dtype)
+ .to(model.device),
+ )
+ for _ in range(num_block_layers)
+ )
+ return past_key_values
+
+
+def prepare_jit_inputs(inputs, model, tokenizer):
+ batch_size = len(inputs)
+ dummy_input = tokenizer.batch_encode_plus(inputs, return_tensors="pt")
+ dummy_input = dummy_input.to(model.device)
+ if model.config.use_cache:
+ dummy_input["past_key_values"] = generate_past_key_values(model, batch_size, 1)
+ dummy_input["attention_mask"] = torch.cat(
+ [
+ torch.zeros(dummy_input["attention_mask"].shape[0], 1)
+ .to(dummy_input["attention_mask"].dtype)
+ .to(model.device),
+ dummy_input["attention_mask"],
+ ],
+ -1,
+ )
+ return dummy_input
+
+
+class _ModelFallbackWrapper(GenerationMixin):
+ __slots__ = ("_optimized", "_default")
+
+ def __init__(self, optimized, default):
+ self._optimized = optimized
+ self._default = default
+
+ def __call__(self, *args, **kwargs):
+ if kwargs["past_key_values"] is None and self._default.config.use_cache:
+ kwargs["past_key_values"] = generate_past_key_values(self._default, kwargs["input_ids"].shape[0], 0)
+ kwargs.pop("position_ids", None)
+ for k in list(kwargs.keys()):
+ if kwargs[k] is None or isinstance(kwargs[k], bool):
+ kwargs.pop(k)
+ outputs = self._optimized(**kwargs)
+ lm_logits = outputs[0]
+ past_key_values = outputs[1]
+ fixed_output = CausalLMOutputWithPast(
+ loss=None,
+ logits=lm_logits,
+ past_key_values=past_key_values,
+ hidden_states=None,
+ attentions=None,
+ )
+ return fixed_output
+
+ def __getattr__(self, item):
+ return getattr(self._default, item)
+
+ def prepare_inputs_for_generation(
+ self, input_ids, past_key_values=None, inputs_embeds=None, use_cache=None, **kwargs
+ ):
+ return self._default.prepare_inputs_for_generation(
+ input_ids, past_key_values=past_key_values, inputs_embeds=inputs_embeds, use_cache=use_cache, **kwargs
+ )
+
+ def _reorder_cache(
+ self, past_key_values: Tuple[Tuple[torch.Tensor]], beam_idx: torch.Tensor
+ ) -> Tuple[Tuple[torch.Tensor]]:
+ """
+ This function is used to re-order the `past_key_values` cache if [`~PretrainedModel.beam_search`] or
+ [`~PretrainedModel.beam_sample`] is called. This is required to match `past_key_values` with the correct
+ beam_idx at every generation step.
+ """
+ return self._default._reorder_cache(past_key_values, beam_idx)
+
+
+def main():
+ parser = argparse.ArgumentParser()
+ parser.add_argument(
+ "--model_type",
+ default=None,
+ type=str,
+ required=True,
+ help="Model type selected in the list: " + ", ".join(MODEL_CLASSES.keys()),
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ default=None,
+ type=str,
+ required=True,
+ help="Path to pre-trained model or shortcut name selected in the list: " + ", ".join(MODEL_CLASSES.keys()),
+ )
+
+ parser.add_argument("--prompt", type=str, default="")
+ parser.add_argument("--length", type=int, default=20)
+ parser.add_argument("--stop_token", type=str, default=None, help="Token at which text generation is stopped")
+
+ parser.add_argument(
+ "--temperature",
+ type=float,
+ default=1.0,
+ help="temperature of 1.0 has no effect, lower tend toward greedy sampling",
+ )
+ parser.add_argument(
+ "--repetition_penalty", type=float, default=1.0, help="primarily useful for CTRL model; in that case, use 1.2"
+ )
+ parser.add_argument("--k", type=int, default=0)
+ parser.add_argument("--p", type=float, default=0.9)
+
+ parser.add_argument("--prefix", type=str, default="", help="Text added prior to input.")
+ parser.add_argument("--padding_text", type=str, default="", help="Deprecated, the use of `--prefix` is preferred.")
+ parser.add_argument("--xlm_language", type=str, default="", help="Optional language when used with the XLM model.")
+
+ parser.add_argument("--seed", type=int, default=42, help="random seed for initialization")
+ parser.add_argument(
+ "--use_cpu",
+ action="store_true",
+ help="Whether or not to use cpu. If set to False, " "we will use gpu/npu or mps device if available",
+ )
+ parser.add_argument("--num_return_sequences", type=int, default=1, help="The number of samples to generate.")
+ parser.add_argument(
+ "--fp16",
+ action="store_true",
+ help="Whether to use 16-bit (mixed) precision (through NVIDIA apex) instead of 32-bit",
+ )
+ parser.add_argument("--jit", action="store_true", help="Whether or not to use jit trace to accelerate inference")
+ args = parser.parse_args()
+
+ # Initialize the distributed state.
+ distributed_state = PartialState(cpu=args.use_cpu)
+
+ logger.warning(f"device: {distributed_state.device}, 16-bits inference: {args.fp16}")
+
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Initialize the model and tokenizer
+ try:
+ args.model_type = args.model_type.lower()
+ model_class, tokenizer_class = MODEL_CLASSES[args.model_type]
+ except KeyError:
+ raise KeyError("the model {} you specified is not supported. You are welcome to add it and open a PR :)")
+
+ tokenizer = tokenizer_class.from_pretrained(args.model_name_or_path)
+ if tokenizer.pad_token is None:
+ tokenizer.pad_token = tokenizer.eos_token
+ model = model_class.from_pretrained(args.model_name_or_path)
+
+ # Set the model to the right device
+ model.to(distributed_state.device)
+
+ if args.fp16:
+ model.half()
+ max_seq_length = getattr(model.config, "max_position_embeddings", 0)
+ args.length = adjust_length_to_model(args.length, max_sequence_length=max_seq_length)
+ logger.info(args)
+
+ prompt_text = args.prompt if args.prompt else input("Model prompt >>> ")
+
+ # Different models need different input formatting and/or extra arguments
+ requires_preprocessing = args.model_type in PREPROCESSING_FUNCTIONS.keys()
+ if requires_preprocessing:
+ prepare_input = PREPROCESSING_FUNCTIONS.get(args.model_type)
+ preprocessed_prompt_text = prepare_input(args, model, tokenizer, prompt_text)
+
+ if model.__class__.__name__ in ["TransfoXLLMHeadModel"]:
+ tokenizer_kwargs = {"add_space_before_punct_symbol": True}
+ else:
+ tokenizer_kwargs = {}
+
+ encoded_prompt = tokenizer.encode(
+ preprocessed_prompt_text, add_special_tokens=False, return_tensors="pt", **tokenizer_kwargs
+ )
+ else:
+ prefix = args.prefix if args.prefix else args.padding_text
+ encoded_prompt = tokenizer.encode(prefix + prompt_text, add_special_tokens=False, return_tensors="pt")
+ encoded_prompt = encoded_prompt.to(distributed_state.device)
+
+ if encoded_prompt.size()[-1] == 0:
+ input_ids = None
+ else:
+ input_ids = encoded_prompt
+
+ if args.jit:
+ jit_input_texts = ["enable jit"]
+ jit_inputs = prepare_jit_inputs(jit_input_texts, model, tokenizer)
+ torch._C._jit_set_texpr_fuser_enabled(False)
+ model.config.return_dict = False
+ if hasattr(model, "forward"):
+ sig = inspect.signature(model.forward)
+ else:
+ sig = inspect.signature(model.__call__)
+ jit_inputs = tuple(jit_inputs[key] for key in sig.parameters if jit_inputs.get(key, None) is not None)
+ traced_model = torch.jit.trace(model, jit_inputs, strict=False)
+ traced_model = torch.jit.freeze(traced_model.eval())
+ traced_model(*jit_inputs)
+ traced_model(*jit_inputs)
+
+ model = _ModelFallbackWrapper(traced_model, model)
+
+ output_sequences = model.generate(
+ input_ids=input_ids,
+ max_length=args.length + len(encoded_prompt[0]),
+ temperature=args.temperature,
+ top_k=args.k,
+ top_p=args.p,
+ repetition_penalty=args.repetition_penalty,
+ do_sample=True,
+ num_return_sequences=args.num_return_sequences,
+ )
+
+ # Remove the batch dimension when returning multiple sequences
+ if len(output_sequences.shape) > 2:
+ output_sequences.squeeze_()
+
+ generated_sequences = []
+
+ for generated_sequence_idx, generated_sequence in enumerate(output_sequences):
+ print(f"=== GENERATED SEQUENCE {generated_sequence_idx + 1} ===")
+ generated_sequence = generated_sequence.tolist()
+
+ # Decode text
+ text = tokenizer.decode(generated_sequence, clean_up_tokenization_spaces=True)
+
+ # Remove all text after the stop token
+ text = text[: text.find(args.stop_token) if args.stop_token else None]
+
+ # Add the prompt at the beginning of the sequence. Remove the excess text that was used for pre-processing
+ total_sequence = (
+ prompt_text + text[len(tokenizer.decode(encoded_prompt[0], clean_up_tokenization_spaces=True)) :]
+ )
+
+ generated_sequences.append(total_sequence)
+ print(total_sequence)
+
+ return generated_sequences
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-generation/run_generation_contrastive_search.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-generation/run_generation_contrastive_search.py
new file mode 100644
index 0000000000000000000000000000000000000000..ba4c9a77e94bed0e6b9336fff275bac09aa02fd4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/text-generation/run_generation_contrastive_search.py
@@ -0,0 +1,136 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2022 University of Cambridge, Tencent AI Lab, DeepMind and The University of Hong Kong Authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""The examples of running contrastive search on the auto-APIs;
+
+Running this example:
+python run_generation_contrastive_search.py --model_name_or_path=openai-community/gpt2-large --penalty_alpha=0.6 --k=4 --length=256
+"""
+
+import argparse
+import logging
+
+from accelerate import PartialState
+from accelerate.utils import set_seed
+
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+
+logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+)
+logger = logging.getLogger(__name__)
+
+
+def main():
+ parser = argparse.ArgumentParser()
+ parser.add_argument(
+ "--model_name_or_path",
+ default=None,
+ type=str,
+ required=True,
+ )
+ parser.add_argument("--prompt", type=str, default="")
+ parser.add_argument("--length", type=int, default=20)
+ parser.add_argument("--stop_token", type=str, default=None, help="Token at which text generation is stopped")
+ parser.add_argument(
+ "--temperature",
+ type=float,
+ default=1.0,
+ help="temperature of 1.0 has no effect, lower tend toward greedy sampling",
+ )
+ parser.add_argument(
+ "--repetition_penalty", type=float, default=1.0, help="primarily useful for CTRL model; in that case, use 1.2"
+ )
+ parser.add_argument("--k", type=int, default=0)
+ parser.add_argument("--penalty_alpha", type=float, default=0.0)
+ parser.add_argument("--p", type=float, default=0.9)
+
+ parser.add_argument("--prefix", type=str, default="", help="Text added prior to input.")
+ parser.add_argument("--padding_text", type=str, default="", help="Deprecated, the use of `--prefix` is preferred.")
+ parser.add_argument("--xlm_language", type=str, default="", help="Optional language when used with the XLM model.")
+
+ parser.add_argument("--seed", type=int, default=42, help="random seed for initialization")
+ parser.add_argument(
+ "--use_cpu",
+ action="store_true",
+ help="Whether or not to use cpu. If set to False, " "we will use gpu/npu or mps device if available",
+ )
+ parser.add_argument(
+ "--fp16",
+ action="store_true",
+ help="Whether to use 16-bit (mixed) precision (through NVIDIA apex) instead of 32-bit",
+ )
+ args = parser.parse_args()
+
+ # Initialize the distributed state.
+ distributed_state = PartialState(cpu=args.use_cpu)
+
+ logger.warning(f"device: {distributed_state.device}, 16-bits inference: {args.fp16}")
+
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Initialize the model and tokenizer
+ tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
+ model = AutoModelForCausalLM.from_pretrained(args.model_name_or_path)
+
+ # tokenizer = GPT2Tokenizer.from_pretrained(args.model_name_or_path)
+ # model = OPTForCausalLM.from_pretrained(args.model_name_or_path)
+ # Set the model to the right device
+ model.to(distributed_state.device)
+
+ if args.fp16:
+ model.half()
+
+ logger.info(args)
+ prompt_text = args.prompt if args.prompt else input("Model prompt >>> ")
+
+ inputs = tokenizer(prompt_text, return_tensors="pt", add_special_tokens=False)
+ inputs = {key: value.to(distributed_state.device) for key, value in inputs.items()}
+
+ output_sequences = model.generate(
+ **inputs,
+ max_length=args.length + len(inputs["input_ids"][0]),
+ penalty_alpha=args.penalty_alpha,
+ top_k=args.k,
+ )
+
+ generated_sequences = []
+ for generated_sequence_idx, generated_sequence in enumerate(output_sequences):
+ print(f"=== GENERATED SEQUENCE {generated_sequence_idx + 1} ===")
+ generated_sequence = generated_sequence.tolist()
+
+ # Decode text
+ text = tokenizer.decode(generated_sequence, clean_up_tokenization_spaces=True, add_special_tokens=False)
+
+ # Remove all text after the stop token
+ text = text[: text.find(args.stop_token) if args.stop_token else None]
+
+ # Add the prompt at the beginning of the sequence. Remove the excess text that was used for pre-processing
+ total_sequence = (
+ prompt_text + text[len(tokenizer.decode(inputs["input_ids"][0], clean_up_tokenization_spaces=True)) :]
+ )
+
+ generated_sequences.append(total_sequence)
+ print(total_sequence)
+
+ return generated_sequences
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..b880b82030792c27e6c446333a221432cab64183
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/README.md
@@ -0,0 +1,146 @@
+
+
+# Token classification
+
+## PyTorch version
+
+Fine-tuning the library models for token classification task such as Named Entity Recognition (NER), Parts-of-speech
+tagging (POS) or phrase extraction (CHUNKS). The main scrip `run_ner.py` leverages the 🤗 Datasets library and the Trainer API. You can easily
+customize it to your needs if you need extra processing on your datasets.
+
+It will either run on a datasets hosted on our [hub](https://huggingface.co/datasets) or with your own text files for
+training and validation, you might just need to add some tweaks in the data preprocessing.
+
+### Using your own data
+
+If you use your own data, the script expects the following format of the data -
+
+```bash
+{
+ "chunk_tags": [11, 12, 12, 21, 13, 11, 11, 21, 13, 11, 12, 13, 11, 21, 22, 11, 12, 17, 11, 21, 17, 11, 12, 12, 21, 22, 22, 13, 11, 0],
+ "id": "0",
+ "ner_tags": [0, 3, 4, 0, 0, 0, 0, 0, 0, 7, 0, 0, 0, 0, 0, 7, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ "pos_tags": [12, 22, 22, 38, 15, 22, 28, 38, 15, 16, 21, 35, 24, 35, 37, 16, 21, 15, 24, 41, 15, 16, 21, 21, 20, 37, 40, 35, 21, 7],
+ "tokens": ["The", "European", "Commission", "said", "on", "Thursday", "it", "disagreed", "with", "German", "advice", "to", "consumers", "to", "shun", "British", "lamb", "until", "scientists", "determine", "whether", "mad", "cow", "disease", "can", "be", "transmitted", "to", "sheep", "."]
+}
+```
+
+The following example fine-tunes BERT on CoNLL-2003:
+
+```bash
+python run_ner.py \
+ --model_name_or_path google-bert/bert-base-uncased \
+ --dataset_name conll2003 \
+ --output_dir /tmp/test-ner \
+ --do_train \
+ --do_eval
+```
+
+or just can just run the bash script `run.sh`.
+
+To run on your own training and validation files, use the following command:
+
+```bash
+python run_ner.py \
+ --model_name_or_path google-bert/bert-base-uncased \
+ --train_file path_to_train_file \
+ --validation_file path_to_validation_file \
+ --output_dir /tmp/test-ner \
+ --do_train \
+ --do_eval
+```
+
+**Note:** This script only works with models that have a fast tokenizer (backed by the 🤗 Tokenizers library) as it
+uses special features of those tokenizers. You can check if your favorite model has a fast tokenizer in
+[this table](https://huggingface.co/transformers/index.html#supported-frameworks), if it doesn't you can still use the old version
+of the script.
+
+> If your model classification head dimensions do not fit the number of labels in the dataset, you can specify `--ignore_mismatched_sizes` to adapt it.
+
+## Old version of the script
+
+You can find the old version of the PyTorch script [here](https://github.com/huggingface/transformers/blob/main/examples/legacy/token-classification/run_ner.py).
+
+## Pytorch version, no Trainer
+
+Based on the script [run_ner_no_trainer.py](https://github.com/huggingface/transformers/blob/main/examples/pytorch/token-classification/run_ner_no_trainer.py).
+
+Like `run_ner.py`, this script allows you to fine-tune any of the models on the [hub](https://huggingface.co/models) on a
+token classification task, either NER, POS or CHUNKS tasks or your own data in a csv or a JSON file. The main difference is that this
+script exposes the bare training loop, to allow you to quickly experiment and add any customization you would like.
+
+It offers less options than the script with `Trainer` (for instance you can easily change the options for the optimizer
+or the dataloaders directly in the script) but still run in a distributed setup, on TPU and supports mixed precision by
+the mean of the [🤗 `Accelerate`](https://github.com/huggingface/accelerate) library. You can use the script normally
+after installing it:
+
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+then
+
+```bash
+export TASK_NAME=ner
+
+python run_ner_no_trainer.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --dataset_name conll2003 \
+ --task_name $TASK_NAME \
+ --max_length 128 \
+ --per_device_train_batch_size 32 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/
+```
+
+You can then use your usual launchers to run in it in a distributed environment, but the easiest way is to run
+
+```bash
+accelerate config
+```
+
+and reply to the questions asked. Then
+
+```bash
+accelerate test
+```
+
+that will check everything is ready for training. Finally, you can launch training with
+
+```bash
+export TASK_NAME=ner
+
+accelerate launch run_ner_no_trainer.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --dataset_name conll2003 \
+ --task_name $TASK_NAME \
+ --max_length 128 \
+ --per_device_train_batch_size 32 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/
+```
+
+This command is the same and will work for:
+
+- a CPU-only setup
+- a setup with one GPU
+- a distributed training with several GPUs (single or multi node)
+- a training on TPUs
+
+Note that this library is in alpha release so your feedback is more than welcome if you encounter any problem using it.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..53740bf4e81aee0c1007c449a9f20420094fa26f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/requirements.txt
@@ -0,0 +1,5 @@
+accelerate >= 0.12.0
+seqeval
+datasets >= 1.8.0
+torch >= 1.3
+evaluate
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/run.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/run.sh
new file mode 100644
index 0000000000000000000000000000000000000000..2dd49117d2d44afb20f64aba6c291e5be340b282
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/run.sh
@@ -0,0 +1,20 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+python3 run_ner.py \
+ --model_name_or_path bert-base-uncased \
+ --dataset_name conll2003 \
+ --output_dir /tmp/test-ner \
+ --do_train \
+ --do_eval
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/run_ner.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/run_ner.py
new file mode 100644
index 0000000000000000000000000000000000000000..81340dc2eef8ad92629013e553635343443cfea5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/run_ner.py
@@ -0,0 +1,651 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2020 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for token classification.
+"""
+# You can also adapt this script on your own token classification task and datasets. Pointers for this are left as
+# comments.
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from typing import Optional
+
+import datasets
+import evaluate
+import numpy as np
+from datasets import ClassLabel, load_dataset
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForTokenClassification,
+ AutoTokenizer,
+ DataCollatorForTokenClassification,
+ HfArgumentParser,
+ PretrainedConfig,
+ PreTrainedTokenizerFast,
+ Trainer,
+ TrainingArguments,
+ set_seed,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/token-classification/requirements.txt")
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+ ignore_mismatched_sizes: bool = field(
+ default=False,
+ metadata={"help": "Will enable to load a pretrained model whose head dimensions are different."},
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ task_name: Optional[str] = field(default="ner", metadata={"help": "The name of the task (ner, pos...)."})
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_file: Optional[str] = field(
+ default=None, metadata={"help": "The input training data file (a csv or JSON file)."}
+ )
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate on (a csv or JSON file)."},
+ )
+ test_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input test data file to predict on (a csv or JSON file)."},
+ )
+ text_column_name: Optional[str] = field(
+ default=None, metadata={"help": "The column name of text to input in the file (a csv or JSON file)."}
+ )
+ label_column_name: Optional[str] = field(
+ default=None, metadata={"help": "The column name of label to input in the file (a csv or JSON file)."}
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ max_seq_length: int = field(
+ default=None,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. If set, sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ pad_to_max_length: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to pad all samples to model maximum sentence length. "
+ "If False, will pad the samples dynamically when batching to the maximum length in the batch. More "
+ "efficient on GPU but very bad for TPU."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_predict_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of prediction examples to this "
+ "value if set."
+ )
+ },
+ )
+ label_all_tokens: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to put the label for one word on all tokens of generated by that word or just on the "
+ "one (in which case the other tokens will have a padding index)."
+ )
+ },
+ )
+ return_entity_level_metrics: bool = field(
+ default=False,
+ metadata={"help": "Whether to return all the entity levels during evaluation or just the overall ones."},
+ )
+
+ def __post_init__(self):
+ if self.dataset_name is None and self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+ self.task_name = self.task_name.lower()
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_ner", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ datasets.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ if data_args.test_file is not None:
+ data_files["test"] = data_args.test_file
+ extension = data_args.test_file.split(".")[-1]
+ raw_datasets = load_dataset(extension, data_files=data_files, cache_dir=model_args.cache_dir)
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ if training_args.do_train:
+ column_names = raw_datasets["train"].column_names
+ features = raw_datasets["train"].features
+ else:
+ column_names = raw_datasets["validation"].column_names
+ features = raw_datasets["validation"].features
+
+ if data_args.text_column_name is not None:
+ text_column_name = data_args.text_column_name
+ elif "tokens" in column_names:
+ text_column_name = "tokens"
+ else:
+ text_column_name = column_names[0]
+
+ if data_args.label_column_name is not None:
+ label_column_name = data_args.label_column_name
+ elif f"{data_args.task_name}_tags" in column_names:
+ label_column_name = f"{data_args.task_name}_tags"
+ else:
+ label_column_name = column_names[1]
+
+ # In the event the labels are not a `Sequence[ClassLabel]`, we will need to go through the dataset to get the
+ # unique labels.
+ def get_label_list(labels):
+ unique_labels = set()
+ for label in labels:
+ unique_labels = unique_labels | set(label)
+ label_list = list(unique_labels)
+ label_list.sort()
+ return label_list
+
+ # If the labels are of type ClassLabel, they are already integers and we have the map stored somewhere.
+ # Otherwise, we have to get the list of labels manually.
+ labels_are_int = isinstance(features[label_column_name].feature, ClassLabel)
+ if labels_are_int:
+ label_list = features[label_column_name].feature.names
+ label_to_id = {i: i for i in range(len(label_list))}
+ else:
+ label_list = get_label_list(raw_datasets["train"][label_column_name])
+ label_to_id = {l: i for i, l in enumerate(label_list)}
+
+ num_labels = len(label_list)
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ num_labels=num_labels,
+ finetuning_task=data_args.task_name,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ tokenizer_name_or_path = model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path
+ if config.model_type in {"bloom", "gpt2", "roberta", "deberta"}:
+ tokenizer = AutoTokenizer.from_pretrained(
+ tokenizer_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=True,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ add_prefix_space=True,
+ )
+ else:
+ tokenizer = AutoTokenizer.from_pretrained(
+ tokenizer_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=True,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ model = AutoModelForTokenClassification.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ ignore_mismatched_sizes=model_args.ignore_mismatched_sizes,
+ )
+
+ # Tokenizer check: this script requires a fast tokenizer.
+ if not isinstance(tokenizer, PreTrainedTokenizerFast):
+ raise ValueError(
+ "This example script only works for models that have a fast tokenizer. Checkout the big table of models at"
+ " https://huggingface.co/transformers/index.html#supported-frameworks to find the model types that meet"
+ " this requirement"
+ )
+
+ # Model has labels -> use them.
+ if model.config.label2id != PretrainedConfig(num_labels=num_labels).label2id:
+ if sorted(model.config.label2id.keys()) == sorted(label_list):
+ # Reorganize `label_list` to match the ordering of the model.
+ if labels_are_int:
+ label_to_id = {i: int(model.config.label2id[l]) for i, l in enumerate(label_list)}
+ label_list = [model.config.id2label[i] for i in range(num_labels)]
+ else:
+ label_list = [model.config.id2label[i] for i in range(num_labels)]
+ label_to_id = {l: i for i, l in enumerate(label_list)}
+ else:
+ logger.warning(
+ "Your model seems to have been trained with labels, but they don't match the dataset: "
+ f"model labels: {sorted(model.config.label2id.keys())}, dataset labels:"
+ f" {sorted(label_list)}.\nIgnoring the model labels as a result.",
+ )
+
+ # Set the correspondences label/ID inside the model config
+ model.config.label2id = {l: i for i, l in enumerate(label_list)}
+ model.config.id2label = dict(enumerate(label_list))
+
+ # Map that sends B-Xxx label to its I-Xxx counterpart
+ b_to_i_label = []
+ for idx, label in enumerate(label_list):
+ if label.startswith("B-") and label.replace("B-", "I-") in label_list:
+ b_to_i_label.append(label_list.index(label.replace("B-", "I-")))
+ else:
+ b_to_i_label.append(idx)
+
+ # Preprocessing the dataset
+ # Padding strategy
+ padding = "max_length" if data_args.pad_to_max_length else False
+
+ # Tokenize all texts and align the labels with them.
+ def tokenize_and_align_labels(examples):
+ tokenized_inputs = tokenizer(
+ examples[text_column_name],
+ padding=padding,
+ truncation=True,
+ max_length=data_args.max_seq_length,
+ # We use this argument because the texts in our dataset are lists of words (with a label for each word).
+ is_split_into_words=True,
+ )
+ labels = []
+ for i, label in enumerate(examples[label_column_name]):
+ word_ids = tokenized_inputs.word_ids(batch_index=i)
+ previous_word_idx = None
+ label_ids = []
+ for word_idx in word_ids:
+ # Special tokens have a word id that is None. We set the label to -100 so they are automatically
+ # ignored in the loss function.
+ if word_idx is None:
+ label_ids.append(-100)
+ # We set the label for the first token of each word.
+ elif word_idx != previous_word_idx:
+ label_ids.append(label_to_id[label[word_idx]])
+ # For the other tokens in a word, we set the label to either the current label or -100, depending on
+ # the label_all_tokens flag.
+ else:
+ if data_args.label_all_tokens:
+ label_ids.append(b_to_i_label[label_to_id[label[word_idx]]])
+ else:
+ label_ids.append(-100)
+ previous_word_idx = word_idx
+
+ labels.append(label_ids)
+ tokenized_inputs["labels"] = labels
+ return tokenized_inputs
+
+ if training_args.do_train:
+ if "train" not in raw_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = raw_datasets["train"]
+ if data_args.max_train_samples is not None:
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+ with training_args.main_process_first(desc="train dataset map pre-processing"):
+ train_dataset = train_dataset.map(
+ tokenize_and_align_labels,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on train dataset",
+ )
+
+ if training_args.do_eval:
+ if "validation" not in raw_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_dataset = raw_datasets["validation"]
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+ with training_args.main_process_first(desc="validation dataset map pre-processing"):
+ eval_dataset = eval_dataset.map(
+ tokenize_and_align_labels,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on validation dataset",
+ )
+
+ if training_args.do_predict:
+ if "test" not in raw_datasets:
+ raise ValueError("--do_predict requires a test dataset")
+ predict_dataset = raw_datasets["test"]
+ if data_args.max_predict_samples is not None:
+ max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
+ predict_dataset = predict_dataset.select(range(max_predict_samples))
+ with training_args.main_process_first(desc="prediction dataset map pre-processing"):
+ predict_dataset = predict_dataset.map(
+ tokenize_and_align_labels,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on prediction dataset",
+ )
+
+ # Data collator
+ data_collator = DataCollatorForTokenClassification(tokenizer, pad_to_multiple_of=8 if training_args.fp16 else None)
+
+ # Metrics
+ metric = evaluate.load("seqeval", cache_dir=model_args.cache_dir)
+
+ def compute_metrics(p):
+ predictions, labels = p
+ predictions = np.argmax(predictions, axis=2)
+
+ # Remove ignored index (special tokens)
+ true_predictions = [
+ [label_list[p] for (p, l) in zip(prediction, label) if l != -100]
+ for prediction, label in zip(predictions, labels)
+ ]
+ true_labels = [
+ [label_list[l] for (p, l) in zip(prediction, label) if l != -100]
+ for prediction, label in zip(predictions, labels)
+ ]
+
+ results = metric.compute(predictions=true_predictions, references=true_labels)
+ if data_args.return_entity_level_metrics:
+ # Unpack nested dictionaries
+ final_results = {}
+ for key, value in results.items():
+ if isinstance(value, dict):
+ for n, v in value.items():
+ final_results[f"{key}_{n}"] = v
+ else:
+ final_results[key] = value
+ return final_results
+ else:
+ return {
+ "precision": results["overall_precision"],
+ "recall": results["overall_recall"],
+ "f1": results["overall_f1"],
+ "accuracy": results["overall_accuracy"],
+ }
+
+ # Initialize our Trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset if training_args.do_train else None,
+ eval_dataset=eval_dataset if training_args.do_eval else None,
+ processing_class=tokenizer,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ metrics = train_result.metrics
+ trainer.save_model() # Saves the tokenizer too for easy upload
+
+ max_train_samples = (
+ data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
+ )
+ metrics["train_samples"] = min(max_train_samples, len(train_dataset))
+
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+
+ metrics = trainer.evaluate()
+
+ max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
+ metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ # Predict
+ if training_args.do_predict:
+ logger.info("*** Predict ***")
+
+ predictions, labels, metrics = trainer.predict(predict_dataset, metric_key_prefix="predict")
+ predictions = np.argmax(predictions, axis=2)
+
+ # Remove ignored index (special tokens)
+ true_predictions = [
+ [label_list[p] for (p, l) in zip(prediction, label) if l != -100]
+ for prediction, label in zip(predictions, labels)
+ ]
+
+ trainer.log_metrics("predict", metrics)
+ trainer.save_metrics("predict", metrics)
+
+ # Save predictions
+ output_predictions_file = os.path.join(training_args.output_dir, "predictions.txt")
+ if trainer.is_world_process_zero():
+ with open(output_predictions_file, "w") as writer:
+ for prediction in true_predictions:
+ writer.write(" ".join(prediction) + "\n")
+
+ kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "token-classification"}
+ if data_args.dataset_name is not None:
+ kwargs["dataset_tags"] = data_args.dataset_name
+ if data_args.dataset_config_name is not None:
+ kwargs["dataset_args"] = data_args.dataset_config_name
+ kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
+ else:
+ kwargs["dataset"] = data_args.dataset_name
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/run_ner_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/run_ner_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..5b8c4c80ef8940e9a7daba4e620ed4fb5e7596ee
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/run_ner_no_trainer.py
@@ -0,0 +1,832 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning a 🤗 Transformers model on token classification tasks (NER, POS, CHUNKS) relying on the accelerate library
+without using a Trainer.
+"""
+
+import argparse
+import json
+import logging
+import math
+import os
+import random
+from pathlib import Path
+
+import datasets
+import evaluate
+import numpy as np
+import torch
+from accelerate import Accelerator
+from accelerate.logging import get_logger
+from accelerate.utils import set_seed
+from datasets import ClassLabel, load_dataset
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from tqdm.auto import tqdm
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ MODEL_MAPPING,
+ AutoConfig,
+ AutoModelForTokenClassification,
+ AutoTokenizer,
+ DataCollatorForTokenClassification,
+ PretrainedConfig,
+ SchedulerType,
+ default_data_collator,
+ get_scheduler,
+)
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+logger = get_logger(__name__)
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/token-classification/requirements.txt")
+
+# You should update this to your particular problem to have better documentation of `model_type`
+MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+def parse_args():
+ parser = argparse.ArgumentParser(
+ description="Finetune a transformers model on a text classification task (NER) with accelerate library"
+ )
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ default=None,
+ help="The name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--dataset_config_name",
+ type=str,
+ default=None,
+ help="The configuration name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
+ )
+ parser.add_argument(
+ "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
+ )
+ parser.add_argument(
+ "--text_column_name",
+ type=str,
+ default=None,
+ help="The column name of text to input in the file (a csv or JSON file).",
+ )
+ parser.add_argument(
+ "--label_column_name",
+ type=str,
+ default=None,
+ help="The column name of label to input in the file (a csv or JSON file).",
+ )
+ parser.add_argument(
+ "--max_length",
+ type=int,
+ default=128,
+ help=(
+ "The maximum total input sequence length after tokenization. Sequences longer than this will be truncated,"
+ " sequences shorter will be padded if `--pad_to_max_length` is passed."
+ ),
+ )
+ parser.add_argument(
+ "--pad_to_max_length",
+ action="store_true",
+ help="If passed, pad all samples to `max_length`. Otherwise, dynamic padding is used.",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=False,
+ )
+ parser.add_argument(
+ "--config_name",
+ type=str,
+ default=None,
+ help="Pretrained config name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ type=str,
+ default=None,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument(
+ "--model_type",
+ type=str,
+ default=None,
+ help="Model type to use if training from scratch.",
+ choices=MODEL_TYPES,
+ )
+ parser.add_argument(
+ "--label_all_tokens",
+ action="store_true",
+ help="Setting labels of all special tokens to -100 and thus PyTorch will ignore them.",
+ )
+ parser.add_argument(
+ "--return_entity_level_metrics",
+ action="store_true",
+ help="Indication whether entity level metrics are to be returner.",
+ )
+ parser.add_argument(
+ "--task_name",
+ type=str,
+ default="ner",
+ choices=["ner", "pos", "chunk"],
+ help="The name of the task.",
+ )
+ parser.add_argument(
+ "--debug",
+ action="store_true",
+ help="Activate debug mode and run training only with a subset of data.",
+ )
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--trust_remote_code",
+ action="store_true",
+ help=(
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ parser.add_argument(
+ "--ignore_mismatched_sizes",
+ action="store_true",
+ help="Whether or not to enable to load a pretrained model whose head dimensions are different.",
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+ if args.task_name is None and args.train_file is None and args.validation_file is None:
+ raise ValueError("Need either a task name or a training/validation file.")
+ else:
+ if args.train_file is not None:
+ extension = args.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if args.validation_file is not None:
+ extension = args.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+
+ if args.push_to_hub:
+ assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
+
+ return args
+
+
+def main():
+ args = parse_args()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_ner_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+ accelerator = (
+ Accelerator(log_with=args.report_to, project_dir=args.output_dir) if args.with_tracking else Accelerator()
+ )
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets for token classification task available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'tokens' or the first column if no column called
+ # 'tokens' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
+ )
+ else:
+ data_files = {}
+ if args.train_file is not None:
+ data_files["train"] = args.train_file
+ extension = args.train_file.split(".")[-1]
+ if args.validation_file is not None:
+ data_files["validation"] = args.validation_file
+ extension = args.validation_file.split(".")[-1]
+ raw_datasets = load_dataset(extension, data_files=data_files)
+ # Trim a number of training examples
+ if args.debug:
+ for split in raw_datasets.keys():
+ raw_datasets[split] = raw_datasets[split].select(range(100))
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ if raw_datasets["train"] is not None:
+ column_names = raw_datasets["train"].column_names
+ features = raw_datasets["train"].features
+ else:
+ column_names = raw_datasets["validation"].column_names
+ features = raw_datasets["validation"].features
+
+ if args.text_column_name is not None:
+ text_column_name = args.text_column_name
+ elif "tokens" in column_names:
+ text_column_name = "tokens"
+ else:
+ text_column_name = column_names[0]
+
+ if args.label_column_name is not None:
+ label_column_name = args.label_column_name
+ elif f"{args.task_name}_tags" in column_names:
+ label_column_name = f"{args.task_name}_tags"
+ else:
+ label_column_name = column_names[1]
+
+ # In the event the labels are not a `Sequence[ClassLabel]`, we will need to go through the dataset to get the
+ # unique labels.
+ def get_label_list(labels):
+ unique_labels = set()
+ for label in labels:
+ unique_labels = unique_labels | set(label)
+ label_list = list(unique_labels)
+ label_list.sort()
+ return label_list
+
+ # If the labels are of type ClassLabel, they are already integers and we have the map stored somewhere.
+ # Otherwise, we have to get the list of labels manually.
+ labels_are_int = isinstance(features[label_column_name].feature, ClassLabel)
+ if labels_are_int:
+ label_list = features[label_column_name].feature.names
+ label_to_id = {i: i for i in range(len(label_list))}
+ else:
+ label_list = get_label_list(raw_datasets["train"][label_column_name])
+ label_to_id = {l: i for i, l in enumerate(label_list)}
+
+ num_labels = len(label_list)
+
+ # Load pretrained model and tokenizer
+ #
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ if args.config_name:
+ config = AutoConfig.from_pretrained(
+ args.config_name, num_labels=num_labels, trust_remote_code=args.trust_remote_code
+ )
+ elif args.model_name_or_path:
+ config = AutoConfig.from_pretrained(
+ args.model_name_or_path, num_labels=num_labels, trust_remote_code=args.trust_remote_code
+ )
+ else:
+ config = CONFIG_MAPPING[args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ tokenizer_name_or_path = args.tokenizer_name if args.tokenizer_name else args.model_name_or_path
+ if not tokenizer_name_or_path:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if config.model_type in {"bloom", "gpt2", "roberta"}:
+ tokenizer = AutoTokenizer.from_pretrained(
+ tokenizer_name_or_path, use_fast=True, add_prefix_space=True, trust_remote_code=args.trust_remote_code
+ )
+ else:
+ tokenizer = AutoTokenizer.from_pretrained(
+ tokenizer_name_or_path, use_fast=True, trust_remote_code=args.trust_remote_code
+ )
+
+ if args.model_name_or_path:
+ model = AutoModelForTokenClassification.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ ignore_mismatched_sizes=args.ignore_mismatched_sizes,
+ trust_remote_code=args.trust_remote_code,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = AutoModelForTokenClassification.from_config(config, trust_remote_code=args.trust_remote_code)
+
+ # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
+ # on a small vocab and want a smaller embedding size, remove this test.
+ embedding_size = model.get_input_embeddings().weight.shape[0]
+ if len(tokenizer) > embedding_size:
+ embedding_size = model.get_input_embeddings().weight.shape[0]
+ if len(tokenizer) > embedding_size:
+ model.resize_token_embeddings(len(tokenizer))
+
+ # Model has labels -> use them.
+ if model.config.label2id != PretrainedConfig(num_labels=num_labels).label2id:
+ if sorted(model.config.label2id.keys()) == sorted(label_list):
+ # Reorganize `label_list` to match the ordering of the model.
+ if labels_are_int:
+ label_to_id = {i: int(model.config.label2id[l]) for i, l in enumerate(label_list)}
+ label_list = [model.config.id2label[i] for i in range(num_labels)]
+ else:
+ label_list = [model.config.id2label[i] for i in range(num_labels)]
+ label_to_id = {l: i for i, l in enumerate(label_list)}
+ else:
+ logger.warning(
+ "Your model seems to have been trained with labels, but they don't match the dataset: "
+ f"model labels: {sorted(model.config.label2id.keys())}, dataset labels:"
+ f" {sorted(label_list)}.\nIgnoring the model labels as a result.",
+ )
+
+ # Set the correspondences label/ID inside the model config
+ model.config.label2id = {l: i for i, l in enumerate(label_list)}
+ model.config.id2label = dict(enumerate(label_list))
+
+ # Map that sends B-Xxx label to its I-Xxx counterpart
+ b_to_i_label = []
+ for idx, label in enumerate(label_list):
+ if label.startswith("B-") and label.replace("B-", "I-") in label_list:
+ b_to_i_label.append(label_list.index(label.replace("B-", "I-")))
+ else:
+ b_to_i_label.append(idx)
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ padding = "max_length" if args.pad_to_max_length else False
+
+ # Tokenize all texts and align the labels with them.
+
+ def tokenize_and_align_labels(examples):
+ tokenized_inputs = tokenizer(
+ examples[text_column_name],
+ max_length=args.max_length,
+ padding=padding,
+ truncation=True,
+ # We use this argument because the texts in our dataset are lists of words (with a label for each word).
+ is_split_into_words=True,
+ )
+
+ labels = []
+ for i, label in enumerate(examples[label_column_name]):
+ word_ids = tokenized_inputs.word_ids(batch_index=i)
+ previous_word_idx = None
+ label_ids = []
+ for word_idx in word_ids:
+ # Special tokens have a word id that is None. We set the label to -100 so they are automatically
+ # ignored in the loss function.
+ if word_idx is None:
+ label_ids.append(-100)
+ # We set the label for the first token of each word.
+ elif word_idx != previous_word_idx:
+ label_ids.append(label_to_id[label[word_idx]])
+ # For the other tokens in a word, we set the label to either the current label or -100, depending on
+ # the label_all_tokens flag.
+ else:
+ if args.label_all_tokens:
+ label_ids.append(b_to_i_label[label_to_id[label[word_idx]]])
+ else:
+ label_ids.append(-100)
+ previous_word_idx = word_idx
+
+ labels.append(label_ids)
+ tokenized_inputs["labels"] = labels
+ return tokenized_inputs
+
+ with accelerator.main_process_first():
+ processed_raw_datasets = raw_datasets.map(
+ tokenize_and_align_labels,
+ batched=True,
+ remove_columns=raw_datasets["train"].column_names,
+ desc="Running tokenizer on dataset",
+ )
+
+ train_dataset = processed_raw_datasets["train"]
+ eval_dataset = processed_raw_datasets["validation"]
+
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ # DataLoaders creation:
+ if args.pad_to_max_length:
+ # If padding was already done ot max length, we use the default data collator that will just convert everything
+ # to tensors.
+ data_collator = default_data_collator
+ else:
+ # Otherwise, `DataCollatorForTokenClassification` will apply dynamic padding for us (by padding to the maximum length of
+ # the samples passed). When using mixed precision, we add `pad_to_multiple_of=8` to pad all tensors to multiple
+ # of 8s, which will enable the use of Tensor Cores on NVIDIA hardware with compute capability >= 7.5 (Volta).
+ # For fp8, we pad to multiple of 16.
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+ data_collator = DataCollatorForTokenClassification(tokenizer, pad_to_multiple_of=pad_to_multiple_of)
+
+ train_dataloader = DataLoader(
+ train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
+ )
+ eval_dataloader = DataLoader(eval_dataset, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size)
+
+ # Optimizer
+ # Split weights in two groups, one with weight decay and the other not.
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
+
+ # Use the device given by the `accelerator` object.
+ device = accelerator.device
+ model.to(device)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps,
+ num_training_steps=args.max_train_steps,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if args.with_tracking:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("ner_no_trainer", experiment_config)
+
+ # Metrics
+ metric = evaluate.load("seqeval")
+
+ def get_labels(predictions, references):
+ # Transform predictions and references tensos to numpy arrays
+ if device.type == "cpu":
+ y_pred = predictions.detach().clone().numpy()
+ y_true = references.detach().clone().numpy()
+ else:
+ y_pred = predictions.detach().cpu().clone().numpy()
+ y_true = references.detach().cpu().clone().numpy()
+
+ # Remove ignored index (special tokens)
+ true_predictions = [
+ [label_list[p] for (p, l) in zip(pred, gold_label) if l != -100]
+ for pred, gold_label in zip(y_pred, y_true)
+ ]
+ true_labels = [
+ [label_list[l] for (p, l) in zip(pred, gold_label) if l != -100]
+ for pred, gold_label in zip(y_pred, y_true)
+ ]
+ return true_predictions, true_labels
+
+ def compute_metrics():
+ results = metric.compute()
+ if args.return_entity_level_metrics:
+ # Unpack nested dictionaries
+ final_results = {}
+ for key, value in results.items():
+ if isinstance(value, dict):
+ for n, v in value.items():
+ final_results[f"{key}_{n}"] = v
+ else:
+ final_results[key] = value
+ return final_results
+ else:
+ return {
+ "precision": results["overall_precision"],
+ "recall": results["overall_recall"],
+ "f1": results["overall_f1"],
+ "accuracy": results["overall_accuracy"],
+ }
+
+ # Train!
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ checkpoint_path = args.resume_from_checkpoint
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ checkpoint_path = path
+ path = os.path.basename(checkpoint_path)
+
+ accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
+ accelerator.load_state(checkpoint_path)
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ completed_steps = resume_step // args.gradient_accumulation_steps
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We skip the first `n` batches in the dataloader when resuming from a checkpoint
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ loss = loss / args.gradient_accumulation_steps
+ accelerator.backward(loss)
+ if step % args.gradient_accumulation_steps == 0 or step == len(train_dataloader) - 1:
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if completed_steps >= args.max_train_steps:
+ break
+
+ model.eval()
+ samples_seen = 0
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = model(**batch)
+ predictions = outputs.logits.argmax(dim=-1)
+ labels = batch["labels"]
+ if not args.pad_to_max_length: # necessary to pad predictions and labels for being gathered
+ predictions = accelerator.pad_across_processes(predictions, dim=1, pad_index=-100)
+ labels = accelerator.pad_across_processes(labels, dim=1, pad_index=-100)
+ predictions_gathered, labels_gathered = accelerator.gather((predictions, labels))
+ # If we are in a multiprocess environment, the last batch has duplicates
+ if accelerator.num_processes > 1:
+ if step == len(eval_dataloader) - 1:
+ predictions_gathered = predictions_gathered[: len(eval_dataloader.dataset) - samples_seen]
+ labels_gathered = labels_gathered[: len(eval_dataloader.dataset) - samples_seen]
+ else:
+ samples_seen += labels_gathered.shape[0]
+ preds, refs = get_labels(predictions_gathered, labels_gathered)
+ metric.add_batch(
+ predictions=preds,
+ references=refs,
+ ) # predictions and preferences are expected to be a nested list of labels, not label_ids
+
+ eval_metric = compute_metrics()
+ accelerator.print(f"epoch {epoch}:", eval_metric)
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "seqeval": eval_metric,
+ "train_loss": total_loss.item() / len(train_dataloader),
+ "epoch": epoch,
+ "step": completed_steps,
+ },
+ step=completed_steps,
+ )
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if args.checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.with_tracking:
+ accelerator.end_training()
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ if args.push_to_hub:
+ api.upload_folder(
+ commit_message="End of training",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ all_results = {f"eval_{k}": v for k, v in eval_metric.items()}
+ if args.with_tracking:
+ all_results.update({"train_loss": total_loss.item() / len(train_dataloader)})
+ with open(os.path.join(args.output_dir, "all_results.json"), "w") as f:
+ # Convert all float64 & int64 type numbers to float & int for json serialization
+ for key, value in all_results.items():
+ if isinstance(value, np.float64):
+ all_results[key] = float(value)
+ elif isinstance(value, np.int64):
+ all_results[key] = int(value)
+ json.dump(all_results, f)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/run_no_trainer.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/run_no_trainer.sh
new file mode 100644
index 0000000000000000000000000000000000000000..bf9cbb7223cbbbb4cbab71a9c32e4170512c3c89
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/token-classification/run_no_trainer.sh
@@ -0,0 +1,21 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+accelerate launch run_ner_no_trainer.py \
+ --model_name_or_path bert-base-uncased \
+ --dataset_name conll2003 \
+ --output_dir /tmp/test-ner \
+ --pad_to_max_length \
+ --task_name ner \
+ --return_entity_level_metrics
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/translation/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/translation/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..74ca16ccb0bf630edc4b5b63099749686233c8ef
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/translation/README.md
@@ -0,0 +1,211 @@
+
+
+## Translation
+
+This directory contains examples for finetuning and evaluating transformers on translation tasks.
+Please tag @patil-suraj with any issues/unexpected behaviors, or send a PR!
+For deprecated `bertabs` instructions, see [`bertabs/README.md`](https://github.com/huggingface/transformers/blob/main/examples/research_projects/bertabs/README.md).
+For the old `finetune_trainer.py` and related utils, see [`examples/legacy/seq2seq`](https://github.com/huggingface/transformers/blob/main/examples/legacy/seq2seq).
+
+### Supported Architectures
+
+- `BartForConditionalGeneration`
+- `FSMTForConditionalGeneration` (translation only)
+- `MBartForConditionalGeneration`
+- `MarianMTModel`
+- `PegasusForConditionalGeneration`
+- `T5ForConditionalGeneration`
+- `MT5ForConditionalGeneration`
+
+`run_translation.py` is a lightweight examples of how to download and preprocess a dataset from the [🤗 Datasets](https://github.com/huggingface/datasets) library or use your own files (jsonlines or csv), then fine-tune one of the architectures above on it.
+
+For custom datasets in `jsonlines` format please see: https://huggingface.co/docs/datasets/loading_datasets#json-files
+and you also will find examples of these below.
+
+
+## With Trainer
+
+Here is an example of a translation fine-tuning with a MarianMT model:
+
+```bash
+python examples/pytorch/translation/run_translation.py \
+ --model_name_or_path Helsinki-NLP/opus-mt-en-ro \
+ --do_train \
+ --do_eval \
+ --source_lang en \
+ --target_lang ro \
+ --dataset_name wmt16 \
+ --dataset_config_name ro-en \
+ --output_dir /tmp/tst-translation \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+MBart and some T5 models require special handling.
+
+T5 models `google-t5/t5-small`, `google-t5/t5-base`, `google-t5/t5-large`, `google-t5/t5-3b` and `google-t5/t5-11b` must use an additional argument: `--source_prefix "translate {source_lang} to {target_lang}"`. For example:
+
+```bash
+python examples/pytorch/translation/run_translation.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --source_lang en \
+ --target_lang ro \
+ --source_prefix "translate English to Romanian: " \
+ --dataset_name wmt16 \
+ --dataset_config_name ro-en \
+ --output_dir /tmp/tst-translation \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+If you get a terrible BLEU score, make sure that you didn't forget to use the `--source_prefix` argument.
+
+For the aforementioned group of T5 models it's important to remember that if you switch to a different language pair, make sure to adjust the source and target values in all 3 language-specific command line argument: `--source_lang`, `--target_lang` and `--source_prefix`.
+
+MBart models require a different format for `--source_lang` and `--target_lang` values, e.g. instead of `en` it expects `en_XX`, for `ro` it expects `ro_RO`. The full MBart specification for language codes can be found [here](https://huggingface.co/facebook/mbart-large-cc25). For example:
+
+```bash
+python examples/pytorch/translation/run_translation.py \
+ --model_name_or_path facebook/mbart-large-en-ro \
+ --do_train \
+ --do_eval \
+ --dataset_name wmt16 \
+ --dataset_config_name ro-en \
+ --source_lang en_XX \
+ --target_lang ro_RO \
+ --output_dir /tmp/tst-translation \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+ ```
+
+And here is how you would use the translation finetuning on your own files, after adjusting the
+values for the arguments `--train_file`, `--validation_file` to match your setup:
+
+```bash
+python examples/pytorch/translation/run_translation.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --source_lang en \
+ --target_lang ro \
+ --source_prefix "translate English to Romanian: " \
+ --dataset_name wmt16 \
+ --dataset_config_name ro-en \
+ --train_file path_to_jsonlines_file \
+ --validation_file path_to_jsonlines_file \
+ --output_dir /tmp/tst-translation \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+The task of translation supports only custom JSONLINES files, with each line being a dictionary with a key `"translation"` and its value another dictionary whose keys is the language pair. For example:
+
+```json
+{ "translation": { "en": "Others have dismissed him as a joke.", "ro": "Alții l-au numit o glumă." } }
+{ "translation": { "en": "And some are holding out for an implosion.", "ro": "Iar alții așteaptă implozia." } }
+```
+Here the languages are Romanian (`ro`) and English (`en`).
+
+If you want to use a pre-processed dataset that leads to high BLEU scores, but for the `en-de` language pair, you can use `--dataset_name stas/wmt14-en-de-pre-processed`, as following:
+
+```bash
+python examples/pytorch/translation/run_translation.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --source_lang en \
+ --target_lang de \
+ --source_prefix "translate English to German: " \
+ --dataset_name stas/wmt14-en-de-pre-processed \
+ --output_dir /tmp/tst-translation \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+ ```
+
+## With Accelerate
+
+Based on the script [`run_translation_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/translation/run_translation_no_trainer.py).
+
+Like `run_translation.py`, this script allows you to fine-tune any of the models supported on a
+translation task, the main difference is that this
+script exposes the bare training loop, to allow you to quickly experiment and add any customization you would like.
+
+It offers less options than the script with `Trainer` (for instance you can easily change the options for the optimizer
+or the dataloaders directly in the script) but still run in a distributed setup, on TPU and supports mixed precision by
+the mean of the [🤗 `Accelerate`](https://github.com/huggingface/accelerate) library. You can use the script normally
+after installing it:
+
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+then
+
+```bash
+python run_translation_no_trainer.py \
+ --model_name_or_path Helsinki-NLP/opus-mt-en-ro \
+ --source_lang en \
+ --target_lang ro \
+ --dataset_name wmt16 \
+ --dataset_config_name ro-en \
+ --output_dir ~/tmp/tst-translation
+```
+
+You can then use your usual launchers to run in it in a distributed environment, but the easiest way is to run
+
+```bash
+accelerate config
+```
+
+and reply to the questions asked. Then
+
+```bash
+accelerate test
+```
+
+that will check everything is ready for training. Finally, you can launch training with
+
+```bash
+accelerate launch run_translation_no_trainer.py \
+ --model_name_or_path Helsinki-NLP/opus-mt-en-ro \
+ --source_lang en \
+ --target_lang ro \
+ --dataset_name wmt16 \
+ --dataset_config_name ro-en \
+ --output_dir ~/tmp/tst-translation
+```
+
+This command is the same and will work for:
+
+- a CPU-only setup
+- a setup with one GPU
+- a distributed training with several GPUs (single or multi node)
+- a training on TPUs
+
+Note that this library is in alpha release so your feedback is more than welcome if you encounter any problem using it.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/translation/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/translation/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..9c9257430c06a832445db13b2446c6ac0bbadbcc
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/translation/requirements.txt
@@ -0,0 +1,8 @@
+accelerate >= 0.12.0
+datasets >= 1.8.0
+sentencepiece != 0.1.92
+protobuf
+sacrebleu >= 1.4.12
+py7zr
+torch >= 1.3
+evaluate
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/translation/run_translation.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/translation/run_translation.py
new file mode 100644
index 0000000000000000000000000000000000000000..1d8ff8d05e530a2c37afc429f09dc612976e6de4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/translation/run_translation.py
@@ -0,0 +1,697 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright The HuggingFace Team and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for sequence to sequence.
+"""
+# You can also adapt this script on your own sequence to sequence task. Pointers for this are left as comments.
+
+import logging
+import os
+import sys
+from dataclasses import dataclass, field
+from typing import Optional
+
+import datasets
+import evaluate
+import numpy as np
+from datasets import load_dataset
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForSeq2SeqLM,
+ AutoTokenizer,
+ DataCollatorForSeq2Seq,
+ HfArgumentParser,
+ M2M100Tokenizer,
+ MBart50Tokenizer,
+ MBart50TokenizerFast,
+ MBartTokenizer,
+ MBartTokenizerFast,
+ Seq2SeqTrainer,
+ Seq2SeqTrainingArguments,
+ default_data_collator,
+ set_seed,
+)
+from transformers.trainer_utils import get_last_checkpoint
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/translation/requirements.txt")
+
+logger = logging.getLogger(__name__)
+
+# A list of all multilingual tokenizer which require src_lang and tgt_lang attributes.
+MULTILINGUAL_TOKENIZERS = [MBartTokenizer, MBartTokenizerFast, MBart50Tokenizer, MBart50TokenizerFast, M2M100Tokenizer]
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where to store the pretrained models downloaded from huggingface.co"},
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ model_revision: str = field(
+ default="main",
+ metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
+ )
+ token: str = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
+ "generated when running `huggingface-cli login` (stored in `~/.huggingface`)."
+ )
+ },
+ )
+ trust_remote_code: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ source_lang: str = field(default=None, metadata={"help": "Source language id for translation."})
+ target_lang: str = field(default=None, metadata={"help": "Target language id for translation."})
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a jsonlines)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": "An optional input evaluation data file to evaluate the metrics (sacrebleu) on a jsonlines file."
+ },
+ )
+ test_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input test data file to evaluate the metrics (sacrebleu) on a jsonlines file."},
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ max_source_length: Optional[int] = field(
+ default=1024,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ max_target_length: Optional[int] = field(
+ default=128,
+ metadata={
+ "help": (
+ "The maximum total sequence length for target text after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ val_max_target_length: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The maximum total sequence length for validation target text after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded. Will default to `max_target_length`. "
+ "This argument is also used to override the ``max_length`` param of ``model.generate``, which is used "
+ "during ``evaluate`` and ``predict``."
+ )
+ },
+ )
+ pad_to_max_length: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to pad all samples to model maximum sentence length. "
+ "If False, will pad the samples dynamically when batching to the maximum length in the batch. More "
+ "efficient on GPU but very bad for TPU."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_predict_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of prediction examples to this "
+ "value if set."
+ )
+ },
+ )
+ num_beams: Optional[int] = field(
+ default=1,
+ metadata={
+ "help": (
+ "Number of beams to use for evaluation. This argument will be passed to ``model.generate``, "
+ "which is used during ``evaluate`` and ``predict``."
+ )
+ },
+ )
+ ignore_pad_token_for_loss: bool = field(
+ default=True,
+ metadata={
+ "help": "Whether to ignore the tokens corresponding to padded labels in the loss computation or not."
+ },
+ )
+ source_prefix: Optional[str] = field(
+ default=None, metadata={"help": "A prefix to add before every source text (useful for T5 models)."}
+ )
+ forced_bos_token: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The token to force as the first generated token after the :obj:`decoder_start_token_id`.Useful for"
+ " multilingual models like :doc:`mBART <../model_doc/mbart>` where the first generated token needs to"
+ " be the target language token.(Usually it is the target language token)"
+ )
+ },
+ )
+
+ def __post_init__(self):
+ if self.dataset_name is None and self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ elif self.source_lang is None or self.target_lang is None:
+ raise ValueError("Need to specify the source language and the target language.")
+
+ # accepting both json and jsonl file extensions, as
+ # many jsonlines files actually have a .json extension
+ valid_extensions = ["json", "jsonl"]
+
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in valid_extensions, "`train_file` should be a jsonlines file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in valid_extensions, "`validation_file` should be a jsonlines file."
+ if self.val_max_target_length is None:
+ self.val_max_target_length = self.max_target_length
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, Seq2SeqTrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_translation", model_args, data_args)
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+ )
+
+ if training_args.should_log:
+ # The default of training_args.log_level is passive, so we set log level at info here to have that default.
+ transformers.utils.logging.set_verbosity_info()
+
+ log_level = training_args.get_process_log_level()
+ logger.setLevel(log_level)
+ datasets.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.set_verbosity(log_level)
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Log on each process the small summary:
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
+ + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
+ )
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ if data_args.source_prefix is None and model_args.model_name_or_path in [
+ "google-t5/t5-small",
+ "google-t5/t5-base",
+ "google-t5/t5-large",
+ "google-t5/t5-3b",
+ "google-t5/t5-11b",
+ ]:
+ logger.warning(
+ "You're running a t5 model but didn't provide a source prefix, which is expected, e.g. with "
+ "`--source_prefix 'translate English to German: ' `"
+ )
+
+ # Detecting last checkpoint.
+ last_checkpoint = None
+ if os.path.isdir(training_args.output_dir) and training_args.do_train and not training_args.overwrite_output_dir:
+ last_checkpoint = get_last_checkpoint(training_args.output_dir)
+ if last_checkpoint is None and len(os.listdir(training_args.output_dir)) > 0:
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+ elif last_checkpoint is not None and training_args.resume_from_checkpoint is None:
+ logger.info(
+ f"Checkpoint detected, resuming training at {last_checkpoint}. To avoid this behavior, change "
+ "the `--output_dir` or add `--overwrite_output_dir` to train from scratch."
+ )
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Get the datasets: you can either provide your own JSON training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For translation, only JSON files are supported, with one field named "translation" containing two keys for the
+ # source and target languages (unless you adapt what follows).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ else:
+ data_files = {}
+ if data_args.train_file is not None:
+ data_files["train"] = data_args.train_file
+ extension = data_args.train_file.split(".")[-1]
+ if data_args.validation_file is not None:
+ data_files["validation"] = data_args.validation_file
+ extension = data_args.validation_file.split(".")[-1]
+ if data_args.test_file is not None:
+ data_files["test"] = data_args.test_file
+ extension = data_args.test_file.split(".")[-1]
+ if extension == "jsonl":
+ builder_name = "json" # the "json" builder reads both .json and .jsonl files
+ else:
+ builder_name = extension # e.g. "parquet"
+ raw_datasets = load_dataset(
+ builder_name,
+ data_files=data_files,
+ cache_dir=model_args.cache_dir,
+ token=model_args.token,
+ )
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading.
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ use_fast=model_args.use_fast_tokenizer,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+ model = AutoModelForSeq2SeqLM.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ revision=model_args.model_revision,
+ token=model_args.token,
+ trust_remote_code=model_args.trust_remote_code,
+ )
+
+ # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
+ # on a small vocab and want a smaller embedding size, remove this test.
+ embedding_size = model.get_input_embeddings().weight.shape[0]
+ if len(tokenizer) > embedding_size:
+ model.resize_token_embeddings(len(tokenizer))
+
+ # Set decoder_start_token_id
+ if model.config.decoder_start_token_id is None and isinstance(tokenizer, (MBartTokenizer, MBartTokenizerFast)):
+ if isinstance(tokenizer, MBartTokenizer):
+ model.config.decoder_start_token_id = tokenizer.lang_code_to_id[data_args.target_lang]
+ else:
+ model.config.decoder_start_token_id = tokenizer.convert_tokens_to_ids(data_args.target_lang)
+
+ if model.config.decoder_start_token_id is None:
+ raise ValueError("Make sure that `config.decoder_start_token_id` is correctly defined")
+
+ prefix = data_args.source_prefix if data_args.source_prefix is not None else ""
+
+ # Preprocessing the datasets.
+ # We need to tokenize inputs and targets.
+ if training_args.do_train:
+ column_names = raw_datasets["train"].column_names
+ elif training_args.do_eval:
+ column_names = raw_datasets["validation"].column_names
+ elif training_args.do_predict:
+ column_names = raw_datasets["test"].column_names
+ else:
+ logger.info("There is nothing to do. Please pass `do_train`, `do_eval` and/or `do_predict`.")
+ return
+
+ # For translation we set the codes of our source and target languages (only useful for mBART, the others will
+ # ignore those attributes).
+ if isinstance(tokenizer, tuple(MULTILINGUAL_TOKENIZERS)):
+ assert data_args.target_lang is not None and data_args.source_lang is not None, (
+ f"{tokenizer.__class__.__name__} is a multilingual tokenizer which requires --source_lang and "
+ "--target_lang arguments."
+ )
+
+ tokenizer.src_lang = data_args.source_lang
+ tokenizer.tgt_lang = data_args.target_lang
+
+ # For multilingual translation models like mBART-50 and M2M100 we need to force the target language token
+ # as the first generated token. We ask the user to explicitly provide this as --forced_bos_token argument.
+ forced_bos_token_id = (
+ tokenizer.lang_code_to_id[data_args.forced_bos_token] if data_args.forced_bos_token is not None else None
+ )
+ model.config.forced_bos_token_id = forced_bos_token_id
+
+ # Get the language codes for input/target.
+ source_lang = data_args.source_lang.split("_")[0]
+ target_lang = data_args.target_lang.split("_")[0]
+
+ # Check the whether the source target length fits in the model, if it has absolute positional embeddings
+ if (
+ hasattr(model.config, "max_position_embeddings")
+ and not hasattr(model.config, "relative_attention_max_distance")
+ and model.config.max_position_embeddings < data_args.max_source_length
+ ):
+ raise ValueError(
+ f"`--max_source_length` is set to {data_args.max_source_length}, but the model only has"
+ f" {model.config.max_position_embeddings} position encodings. Consider either reducing"
+ f" `--max_source_length` to {model.config.max_position_embeddings} or using a model with larger position "
+ "embeddings"
+ )
+
+ # Temporarily set max_target_length for training.
+ max_target_length = data_args.max_target_length
+ padding = "max_length" if data_args.pad_to_max_length else False
+
+ if training_args.label_smoothing_factor > 0 and not hasattr(model, "prepare_decoder_input_ids_from_labels"):
+ logger.warning(
+ "label_smoothing is enabled but the `prepare_decoder_input_ids_from_labels` method is not defined for "
+ f"`{model.__class__.__name__}`. This will lead to loss being calculated twice and will take up more memory"
+ )
+
+ def preprocess_function(examples):
+ inputs = [ex[source_lang] for ex in examples["translation"]]
+ targets = [ex[target_lang] for ex in examples["translation"]]
+ inputs = [prefix + inp for inp in inputs]
+ model_inputs = tokenizer(inputs, max_length=data_args.max_source_length, padding=padding, truncation=True)
+
+ # Tokenize targets with the `text_target` keyword argument
+ labels = tokenizer(text_target=targets, max_length=max_target_length, padding=padding, truncation=True)
+
+ # If we are padding here, replace all tokenizer.pad_token_id in the labels by -100 when we want to ignore
+ # padding in the loss.
+ if padding == "max_length" and data_args.ignore_pad_token_for_loss:
+ labels["input_ids"] = [
+ [(l if l != tokenizer.pad_token_id else -100) for l in label] for label in labels["input_ids"]
+ ]
+
+ model_inputs["labels"] = labels["input_ids"]
+ return model_inputs
+
+ if training_args.do_train:
+ if "train" not in raw_datasets:
+ raise ValueError("--do_train requires a train dataset")
+ train_dataset = raw_datasets["train"]
+ if data_args.max_train_samples is not None:
+ max_train_samples = min(len(train_dataset), data_args.max_train_samples)
+ train_dataset = train_dataset.select(range(max_train_samples))
+ with training_args.main_process_first(desc="train dataset map pre-processing"):
+ train_dataset = train_dataset.map(
+ preprocess_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on train dataset",
+ )
+
+ if training_args.do_eval:
+ max_target_length = data_args.val_max_target_length
+ if "validation" not in raw_datasets:
+ raise ValueError("--do_eval requires a validation dataset")
+ eval_dataset = raw_datasets["validation"]
+ if data_args.max_eval_samples is not None:
+ max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
+ eval_dataset = eval_dataset.select(range(max_eval_samples))
+ with training_args.main_process_first(desc="validation dataset map pre-processing"):
+ eval_dataset = eval_dataset.map(
+ preprocess_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on validation dataset",
+ )
+
+ if training_args.do_predict:
+ max_target_length = data_args.val_max_target_length
+ if "test" not in raw_datasets:
+ raise ValueError("--do_predict requires a test dataset")
+ predict_dataset = raw_datasets["test"]
+ if data_args.max_predict_samples is not None:
+ max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
+ predict_dataset = predict_dataset.select(range(max_predict_samples))
+ with training_args.main_process_first(desc="prediction dataset map pre-processing"):
+ predict_dataset = predict_dataset.map(
+ preprocess_function,
+ batched=True,
+ num_proc=data_args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not data_args.overwrite_cache,
+ desc="Running tokenizer on prediction dataset",
+ )
+
+ # Data collator
+ label_pad_token_id = -100 if data_args.ignore_pad_token_for_loss else tokenizer.pad_token_id
+ if data_args.pad_to_max_length:
+ data_collator = default_data_collator
+ else:
+ data_collator = DataCollatorForSeq2Seq(
+ tokenizer,
+ model=model,
+ label_pad_token_id=label_pad_token_id,
+ pad_to_multiple_of=8 if training_args.fp16 else None,
+ )
+
+ # Metric
+ metric = evaluate.load("sacrebleu", cache_dir=model_args.cache_dir)
+
+ def postprocess_text(preds, labels):
+ preds = [pred.strip() for pred in preds]
+ labels = [[label.strip()] for label in labels]
+
+ return preds, labels
+
+ def compute_metrics(eval_preds):
+ preds, labels = eval_preds
+ if isinstance(preds, tuple):
+ preds = preds[0]
+ # Replace -100s used for padding as we can't decode them
+ preds = np.where(preds != -100, preds, tokenizer.pad_token_id)
+ decoded_preds = tokenizer.batch_decode(preds, skip_special_tokens=True)
+ labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
+ decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+ # Some simple post-processing
+ decoded_preds, decoded_labels = postprocess_text(decoded_preds, decoded_labels)
+
+ result = metric.compute(predictions=decoded_preds, references=decoded_labels)
+ result = {"bleu": result["score"]}
+
+ prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in preds]
+ result["gen_len"] = np.mean(prediction_lens)
+ result = {k: round(v, 4) for k, v in result.items()}
+ return result
+
+ # Initialize our Trainer
+ trainer = Seq2SeqTrainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset if training_args.do_train else None,
+ eval_dataset=eval_dataset if training_args.do_eval else None,
+ processing_class=tokenizer,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics if training_args.predict_with_generate else None,
+ )
+
+ # Training
+ if training_args.do_train:
+ checkpoint = None
+ if training_args.resume_from_checkpoint is not None:
+ checkpoint = training_args.resume_from_checkpoint
+ elif last_checkpoint is not None:
+ checkpoint = last_checkpoint
+ train_result = trainer.train(resume_from_checkpoint=checkpoint)
+ trainer.save_model() # Saves the tokenizer too for easy upload
+
+ metrics = train_result.metrics
+ max_train_samples = (
+ data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
+ )
+ metrics["train_samples"] = min(max_train_samples, len(train_dataset))
+
+ trainer.log_metrics("train", metrics)
+ trainer.save_metrics("train", metrics)
+ trainer.save_state()
+
+ # Evaluation
+ results = {}
+ max_length = (
+ training_args.generation_max_length
+ if training_args.generation_max_length is not None
+ else data_args.val_max_target_length
+ )
+ num_beams = data_args.num_beams if data_args.num_beams is not None else training_args.generation_num_beams
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+
+ metrics = trainer.evaluate(max_length=max_length, num_beams=num_beams, metric_key_prefix="eval")
+ max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
+ metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
+
+ trainer.log_metrics("eval", metrics)
+ trainer.save_metrics("eval", metrics)
+
+ if training_args.do_predict:
+ logger.info("*** Predict ***")
+
+ predict_results = trainer.predict(
+ predict_dataset, metric_key_prefix="predict", max_length=max_length, num_beams=num_beams
+ )
+ metrics = predict_results.metrics
+ max_predict_samples = (
+ data_args.max_predict_samples if data_args.max_predict_samples is not None else len(predict_dataset)
+ )
+ metrics["predict_samples"] = min(max_predict_samples, len(predict_dataset))
+
+ trainer.log_metrics("predict", metrics)
+ trainer.save_metrics("predict", metrics)
+
+ if trainer.is_world_process_zero():
+ if training_args.predict_with_generate:
+ predictions = predict_results.predictions
+ predictions = np.where(predictions != -100, predictions, tokenizer.pad_token_id)
+ predictions = tokenizer.batch_decode(
+ predictions, skip_special_tokens=True, clean_up_tokenization_spaces=True
+ )
+ predictions = [pred.strip() for pred in predictions]
+ output_prediction_file = os.path.join(training_args.output_dir, "generated_predictions.txt")
+ with open(output_prediction_file, "w", encoding="utf-8") as writer:
+ writer.write("\n".join(predictions))
+
+ kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "translation"}
+ if data_args.dataset_name is not None:
+ kwargs["dataset_tags"] = data_args.dataset_name
+ if data_args.dataset_config_name is not None:
+ kwargs["dataset_args"] = data_args.dataset_config_name
+ kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
+ else:
+ kwargs["dataset"] = data_args.dataset_name
+
+ languages = [l for l in [data_args.source_lang, data_args.target_lang] if l is not None]
+ if len(languages) > 0:
+ kwargs["language"] = languages
+
+ if training_args.push_to_hub:
+ trainer.push_to_hub(**kwargs)
+ else:
+ trainer.create_model_card(**kwargs)
+
+ return results
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/translation/run_translation_no_trainer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/translation/run_translation_no_trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..502132143046929360239248c33269f3aec9b3f1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/translation/run_translation_no_trainer.py
@@ -0,0 +1,790 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright The HuggingFace Team and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning a 🤗 Transformers model on text translation.
+"""
+# You can also adapt this script on your own text translation task. Pointers for this are left as comments.
+
+import argparse
+import json
+import logging
+import math
+import os
+import random
+from pathlib import Path
+
+import datasets
+import evaluate
+import numpy as np
+import torch
+from accelerate import Accelerator
+from accelerate.logging import get_logger
+from accelerate.utils import set_seed
+from datasets import load_dataset
+from huggingface_hub import HfApi
+from torch.utils.data import DataLoader
+from tqdm.auto import tqdm
+
+import transformers
+from transformers import (
+ CONFIG_MAPPING,
+ MODEL_MAPPING,
+ AutoConfig,
+ AutoModelForSeq2SeqLM,
+ AutoTokenizer,
+ DataCollatorForSeq2Seq,
+ MBartTokenizer,
+ MBartTokenizerFast,
+ SchedulerType,
+ default_data_collator,
+ get_scheduler,
+)
+from transformers.utils import check_min_version, send_example_telemetry
+from transformers.utils.versions import require_version
+
+
+# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
+check_min_version("4.49.0.dev0")
+
+logger = get_logger(__name__)
+require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/translation/requirements.txt")
+
+# You should update this to your particular problem to have better documentation of `model_type`
+MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+# Parsing input arguments
+def parse_args():
+ parser = argparse.ArgumentParser(description="Finetune a transformers model on a text classification task")
+ parser.add_argument(
+ "--dataset_name",
+ type=str,
+ default=None,
+ help="The name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--predict_with_generate",
+ type=bool,
+ default=True,
+ help="",
+ )
+ parser.add_argument(
+ "--dataset_config_name",
+ type=str,
+ default=None,
+ help="The configuration name of the dataset to use (via the datasets library).",
+ )
+ parser.add_argument(
+ "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
+ )
+
+ parser.add_argument(
+ "--num_beams",
+ type=int,
+ default=None,
+ help=(
+ "Number of beams to use for evaluation. This argument will be "
+ "passed to ``model.generate``, which is used during ``evaluate`` and ``predict``."
+ ),
+ )
+
+ parser.add_argument(
+ "--max_source_length",
+ type=int,
+ default=1024,
+ help=(
+ "The maximum total input sequence length after "
+ "tokenization.Sequences longer than this will be truncated, sequences shorter will be padded."
+ ),
+ )
+ parser.add_argument(
+ "--max_target_length",
+ type=int,
+ default=128,
+ help=(
+ "The maximum total sequence length for target text after "
+ "tokenization. Sequences longer than this will be truncated, sequences shorter will be padded "
+ "during ``evaluate`` and ``predict``."
+ ),
+ )
+ parser.add_argument(
+ "--val_max_target_length",
+ type=int,
+ default=None,
+ help=(
+ "The maximum total sequence length for validation "
+ "target text after tokenization.Sequences longer than this will be truncated, sequences shorter will be "
+ "padded. Will default to `max_target_length`.This argument is also used to override the ``max_length`` "
+ "param of ``model.generate``, which is used during ``evaluate`` and ``predict``."
+ ),
+ )
+ parser.add_argument(
+ "--pad_to_max_length",
+ type=bool,
+ default=False,
+ help=(
+ "Whether to pad all samples to model maximum sentence "
+ "length. If False, will pad the samples dynamically when batching to the maximum length in the batch. More "
+ "efficient on GPU but very bad for TPU."
+ ),
+ )
+ parser.add_argument(
+ "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
+ )
+ parser.add_argument(
+ "--ignore_pad_token_for_loss",
+ type=bool,
+ default=True,
+ help="Whether to ignore the tokens corresponding to padded labels in the loss computation or not.",
+ )
+ parser.add_argument("--source_lang", type=str, default=None, help="Source language id for translation.")
+ parser.add_argument("--target_lang", type=str, default=None, help="Target language id for translation.")
+ parser.add_argument(
+ "--source_prefix",
+ type=str,
+ default=None,
+ help="A prefix to add before every source text (useful for T5 models).",
+ )
+ parser.add_argument(
+ "--preprocessing_num_workers",
+ type=int,
+ default=None,
+ help="The number of processes to use for the preprocessing.",
+ )
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+ parser.add_argument(
+ "--max_length",
+ type=int,
+ default=128,
+ help=(
+ "The maximum total input sequence length after tokenization. Sequences longer than this will be truncated,"
+ " sequences shorter will be padded if `--pad_to_max_length` is passed."
+ ),
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ type=str,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ required=False,
+ )
+ parser.add_argument(
+ "--config_name",
+ type=str,
+ default=None,
+ help="Pretrained config name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ type=str,
+ default=None,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--use_slow_tokenizer",
+ action="store_true",
+ help="If passed, will use a slow tokenizer (not backed by the 🤗 Tokenizers library).",
+ )
+ parser.add_argument(
+ "--per_device_train_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the training dataloader.",
+ )
+ parser.add_argument(
+ "--per_device_eval_batch_size",
+ type=int,
+ default=8,
+ help="Batch size (per device) for the evaluation dataloader.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=5e-5,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
+ parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--lr_scheduler_type",
+ type=SchedulerType,
+ default="linear",
+ help="The scheduler type to use.",
+ choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
+ )
+ parser.add_argument(
+ "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument(
+ "--model_type",
+ type=str,
+ default=None,
+ help="Model type to use if training from scratch.",
+ choices=MODEL_TYPES,
+ )
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument(
+ "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
+ )
+ parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--trust_remote_code",
+ action="store_true",
+ help=(
+ "Whether to trust the execution of code from datasets/models defined on the Hub."
+ " This option should only be set to `True` for repositories you trust and in which you have read the"
+ " code, as it will execute code present on the Hub on your local machine."
+ ),
+ )
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=str,
+ default=None,
+ help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help="If the training should continue from a checkpoint folder.",
+ )
+ parser.add_argument(
+ "--with_tracking",
+ action="store_true",
+ help="Whether to enable experiment trackers for logging.",
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="all",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
+ ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
+ "Only applicable when `--with_tracking` is passed."
+ ),
+ )
+ args = parser.parse_args()
+
+ # Sanity checks
+
+ if args.dataset_name is None and args.train_file is None and args.validation_file is None:
+ raise ValueError("Need either a task name or a training/validation file.")
+
+ if args.train_file is not None:
+ extension = args.train_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
+ if args.validation_file is not None:
+ extension = args.validation_file.split(".")[-1]
+ assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
+
+ if args.push_to_hub:
+ assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
+
+ return args
+
+
+def main():
+ # Parse the arguments
+ args = parse_args()
+
+ # Sending telemetry. Tracking the example usage helps us better allocate resources to maintain them. The
+ # information sent is the one passed as arguments along with your Python/PyTorch versions.
+ send_example_telemetry("run_translation_no_trainer", args)
+
+ # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
+ # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
+ # in the environment
+ accelerator = (
+ Accelerator(log_with=args.report_to, project_dir=args.output_dir) if args.with_tracking else Accelerator()
+ )
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.push_to_hub:
+ # Retrieve of infer repo_name
+ repo_name = args.hub_model_id
+ if repo_name is None:
+ repo_name = Path(args.output_dir).absolute().name
+ # Create repo and retrieve repo_id
+ api = HfApi()
+ repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
+
+ with open(os.path.join(args.output_dir, ".gitignore"), "w+") as gitignore:
+ if "step_*" not in gitignore:
+ gitignore.write("step_*\n")
+ if "epoch_*" not in gitignore:
+ gitignore.write("epoch_*\n")
+ elif args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.wait_for_everyone()
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ #
+ # In distributed training, the load_dataset function guarantee that only one local process can concurrently
+ # download the dataset.
+ if args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ raw_datasets = load_dataset(
+ args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
+ )
+ else:
+ data_files = {}
+ if args.train_file is not None:
+ data_files["train"] = args.train_file
+ extension = args.train_file.split(".")[-1]
+ if args.validation_file is not None:
+ data_files["validation"] = args.validation_file
+ extension = args.validation_file.split(".")[-1]
+ raw_datasets = load_dataset(extension, data_files=data_files)
+ # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
+ # https://huggingface.co/docs/datasets/loading_datasets.
+
+ # Load pretrained model and tokenizer
+ #
+ # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+ if args.config_name:
+ config = AutoConfig.from_pretrained(args.config_name, trust_remote_code=args.trust_remote_code)
+ elif args.model_name_or_path:
+ config = AutoConfig.from_pretrained(args.model_name_or_path, trust_remote_code=args.trust_remote_code)
+ else:
+ config = CONFIG_MAPPING[args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ if args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.tokenizer_name, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
+ )
+ elif args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.model_name_or_path, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
+ )
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ if args.model_name_or_path:
+ model = AutoModelForSeq2SeqLM.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ trust_remote_code=args.trust_remote_code,
+ )
+ else:
+ logger.info("Training new model from scratch")
+ model = AutoModelForSeq2SeqLM.from_config(config, trust_remote_code=args.trust_remote_code)
+
+ # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
+ # on a small vocab and want a smaller embedding size, remove this test.
+ embedding_size = model.get_input_embeddings().weight.shape[0]
+ if len(tokenizer) > embedding_size:
+ model.resize_token_embeddings(len(tokenizer))
+
+ # Set decoder_start_token_id
+ if model.config.decoder_start_token_id is None and isinstance(tokenizer, (MBartTokenizer, MBartTokenizerFast)):
+ assert (
+ args.target_lang is not None and args.source_lang is not None
+ ), "mBart requires --target_lang and --source_lang"
+ if isinstance(tokenizer, MBartTokenizer):
+ model.config.decoder_start_token_id = tokenizer.lang_code_to_id[args.target_lang]
+ else:
+ model.config.decoder_start_token_id = tokenizer.convert_tokens_to_ids(args.target_lang)
+
+ if model.config.decoder_start_token_id is None:
+ raise ValueError("Make sure that `config.decoder_start_token_id` is correctly defined")
+
+ prefix = args.source_prefix if args.source_prefix is not None else ""
+
+ # Preprocessing the datasets.
+ # First we tokenize all the texts.
+ column_names = raw_datasets["train"].column_names
+
+ # For translation we set the codes of our source and target languages (only useful for mBART, the others will
+ # ignore those attributes).
+ if isinstance(tokenizer, (MBartTokenizer, MBartTokenizerFast)):
+ if args.source_lang is not None:
+ tokenizer.src_lang = args.source_lang
+ if args.target_lang is not None:
+ tokenizer.tgt_lang = args.target_lang
+
+ # Get the language codes for input/target.
+ source_lang = args.source_lang.split("_")[0]
+ target_lang = args.target_lang.split("_")[0]
+
+ padding = "max_length" if args.pad_to_max_length else False
+
+ # Temporarily set max_target_length for training.
+ max_target_length = args.max_target_length
+ padding = "max_length" if args.pad_to_max_length else False
+
+ def preprocess_function(examples):
+ inputs = [ex[source_lang] for ex in examples["translation"]]
+ targets = [ex[target_lang] for ex in examples["translation"]]
+ inputs = [prefix + inp for inp in inputs]
+ model_inputs = tokenizer(inputs, max_length=args.max_source_length, padding=padding, truncation=True)
+
+ # Tokenize targets with the `text_target` keyword argument
+ labels = tokenizer(text_target=targets, max_length=max_target_length, padding=padding, truncation=True)
+
+ # If we are padding here, replace all tokenizer.pad_token_id in the labels by -100 when we want to ignore
+ # padding in the loss.
+ if padding == "max_length" and args.ignore_pad_token_for_loss:
+ labels["input_ids"] = [
+ [(l if l != tokenizer.pad_token_id else -100) for l in label] for label in labels["input_ids"]
+ ]
+
+ model_inputs["labels"] = labels["input_ids"]
+ return model_inputs
+
+ with accelerator.main_process_first():
+ processed_datasets = raw_datasets.map(
+ preprocess_function,
+ batched=True,
+ num_proc=args.preprocessing_num_workers,
+ remove_columns=column_names,
+ load_from_cache_file=not args.overwrite_cache,
+ desc="Running tokenizer on dataset",
+ )
+
+ train_dataset = processed_datasets["train"]
+ eval_dataset = processed_datasets["validation"]
+
+ # Log a few random samples from the training set:
+ for index in random.sample(range(len(train_dataset)), 3):
+ logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
+
+ # DataLoaders creation:
+ label_pad_token_id = -100 if args.ignore_pad_token_for_loss else tokenizer.pad_token_id
+ if args.pad_to_max_length:
+ # If padding was already done ot max length, we use the default data collator that will just convert everything
+ # to tensors.
+ data_collator = default_data_collator
+ else:
+ # Otherwise, `DataCollatorWithPadding` will apply dynamic padding for us (by padding to the maximum length of
+ # the samples passed). When using mixed precision, we add `pad_to_multiple_of=8` to pad all tensors to multiple
+ # of 8s, which will enable the use of Tensor Cores on NVIDIA hardware with compute capability >= 7.5 (Volta).
+ # For fp8, we pad to multiple of 16.
+ if accelerator.mixed_precision == "fp8":
+ pad_to_multiple_of = 16
+ elif accelerator.mixed_precision != "no":
+ pad_to_multiple_of = 8
+ else:
+ pad_to_multiple_of = None
+ data_collator = DataCollatorForSeq2Seq(
+ tokenizer,
+ model=model,
+ label_pad_token_id=label_pad_token_id,
+ pad_to_multiple_of=pad_to_multiple_of,
+ )
+
+ train_dataloader = DataLoader(
+ train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
+ )
+ eval_dataloader = DataLoader(eval_dataset, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size)
+
+ # Optimizer
+ # Split weights in two groups, one with weight decay and the other not.
+ no_decay = ["bias", "LayerNorm.weight", "layer_norm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ ]
+ optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps,
+ num_training_steps=args.max_train_steps,
+ )
+
+ # Prepare everything with our `accelerator`.
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
+ )
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+ # Figure out how many steps we should save the Accelerator states
+ checkpointing_steps = args.checkpointing_steps
+ if checkpointing_steps is not None and checkpointing_steps.isdigit():
+ checkpointing_steps = int(checkpointing_steps)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # We initialize the trackers only on main process because `accelerator.log`
+ # only logs on main process and we don't want empty logs/runs on other processes.
+ if args.with_tracking:
+ if accelerator.is_main_process:
+ experiment_config = vars(args)
+ # TensorBoard cannot log Enums, need the raw value
+ experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
+ accelerator.init_trackers("translation_no_trainer", experiment_config)
+
+ metric = evaluate.load("sacrebleu")
+
+ def postprocess_text(preds, labels):
+ preds = [pred.strip() for pred in preds]
+ labels = [[label.strip()] for label in labels]
+
+ return preds, labels
+
+ # Train!
+ total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
+ completed_steps = 0
+ starting_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ checkpoint_path = args.resume_from_checkpoint
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ checkpoint_path = path
+ path = os.path.basename(checkpoint_path)
+
+ accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
+ accelerator.load_state(checkpoint_path)
+ # Extract `epoch_{i}` or `step_{i}`
+ training_difference = os.path.splitext(path)[0]
+
+ if "epoch" in training_difference:
+ starting_epoch = int(training_difference.replace("epoch_", "")) + 1
+ resume_step = None
+ completed_steps = starting_epoch * num_update_steps_per_epoch
+ else:
+ # need to multiply `gradient_accumulation_steps` to reflect real steps
+ resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
+ starting_epoch = resume_step // len(train_dataloader)
+ completed_steps = resume_step // args.gradient_accumulation_steps
+ resume_step -= starting_epoch * len(train_dataloader)
+
+ # update the progress_bar if load from checkpoint
+ progress_bar.update(completed_steps)
+
+ for epoch in range(starting_epoch, args.num_train_epochs):
+ model.train()
+ if args.with_tracking:
+ total_loss = 0
+ if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
+ # We skip the first `n` batches in the dataloader when resuming from a checkpoint
+ active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
+ else:
+ active_dataloader = train_dataloader
+ for step, batch in enumerate(active_dataloader):
+ outputs = model(**batch)
+ loss = outputs.loss
+ # We keep track of the loss at each epoch
+ if args.with_tracking:
+ total_loss += loss.detach().float()
+ loss = loss / args.gradient_accumulation_steps
+ accelerator.backward(loss)
+ if step % args.gradient_accumulation_steps == 0 or step == len(train_dataloader) - 1:
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ progress_bar.update(1)
+ completed_steps += 1
+
+ if isinstance(checkpointing_steps, int):
+ if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
+ output_dir = f"step_{completed_steps}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if completed_steps >= args.max_train_steps:
+ break
+
+ model.eval()
+
+ if args.val_max_target_length is None:
+ args.val_max_target_length = args.max_target_length
+
+ gen_kwargs = {
+ "max_length": args.val_max_target_length if args is not None else config.max_length,
+ "num_beams": args.num_beams,
+ }
+ samples_seen = 0
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ generated_tokens = accelerator.unwrap_model(model).generate(
+ batch["input_ids"],
+ attention_mask=batch["attention_mask"],
+ **gen_kwargs,
+ )
+
+ generated_tokens = accelerator.pad_across_processes(
+ generated_tokens, dim=1, pad_index=tokenizer.pad_token_id
+ )
+ labels = batch["labels"]
+ if not args.pad_to_max_length:
+ # If we did not pad to max length, we need to pad the labels too
+ labels = accelerator.pad_across_processes(batch["labels"], dim=1, pad_index=tokenizer.pad_token_id)
+
+ generated_tokens = accelerator.gather(generated_tokens).cpu().numpy()
+ labels = accelerator.gather(labels).cpu().numpy()
+
+ if args.ignore_pad_token_for_loss:
+ # Replace -100 in the labels as we can't decode them.
+ labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
+
+ decoded_preds = tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+ decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+ decoded_preds, decoded_labels = postprocess_text(decoded_preds, decoded_labels)
+
+ # If we are in a multiprocess environment, the last batch has duplicates
+ if accelerator.num_processes > 1:
+ if step == len(eval_dataloader) - 1:
+ decoded_preds = decoded_preds[: len(eval_dataloader.dataset) - samples_seen]
+ decoded_labels = decoded_labels[: len(eval_dataloader.dataset) - samples_seen]
+ else:
+ samples_seen += len(decoded_labels)
+
+ metric.add_batch(predictions=decoded_preds, references=decoded_labels)
+ eval_metric = metric.compute()
+ logger.info({"bleu": eval_metric["score"]})
+
+ if args.with_tracking:
+ accelerator.log(
+ {
+ "bleu": eval_metric["score"],
+ "train_loss": total_loss.item() / len(train_dataloader),
+ "epoch": epoch,
+ "step": completed_steps,
+ },
+ step=completed_steps,
+ )
+
+ if args.push_to_hub and epoch < args.num_train_epochs - 1:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ api.upload_folder(
+ commit_message=f"Training in progress epoch {epoch}",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+
+ if args.checkpointing_steps == "epoch":
+ output_dir = f"epoch_{epoch}"
+ if args.output_dir is not None:
+ output_dir = os.path.join(args.output_dir, output_dir)
+ accelerator.save_state(output_dir)
+
+ if args.with_tracking:
+ accelerator.end_training()
+
+ if args.output_dir is not None:
+ accelerator.wait_for_everyone()
+ unwrapped_model = accelerator.unwrap_model(model)
+ unwrapped_model.save_pretrained(
+ args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
+ )
+ if accelerator.is_main_process:
+ tokenizer.save_pretrained(args.output_dir)
+ if args.push_to_hub:
+ api.upload_folder(
+ commit_message="End of training",
+ folder_path=args.output_dir,
+ repo_id=repo_id,
+ repo_type="model",
+ token=args.hub_token,
+ )
+ with open(os.path.join(args.output_dir, "all_results.json"), "w") as f:
+ json.dump({"eval_bleu": eval_metric["score"]}, f)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/xla_spawn.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/xla_spawn.py
new file mode 100644
index 0000000000000000000000000000000000000000..f9955acfa201a77b12ab4391c14190434e748bbb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/pytorch/xla_spawn.py
@@ -0,0 +1,82 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+A simple launcher script for TPU training
+
+Inspired by https://github.com/pytorch/pytorch/blob/master/torch/distributed/launch.py
+
+::
+ >>> python xla_spawn.py --num_cores=NUM_CORES_YOU_HAVE
+ YOUR_TRAINING_SCRIPT.py (--arg1 --arg2 --arg3 and all other
+ arguments of your training script)
+
+"""
+
+import importlib
+import sys
+from argparse import REMAINDER, ArgumentParser
+from pathlib import Path
+
+import torch_xla.distributed.xla_multiprocessing as xmp
+
+
+def parse_args():
+ """
+ Helper function parsing the command line options
+ @retval ArgumentParser
+ """
+ parser = ArgumentParser(
+ description=(
+ "PyTorch TPU distributed training launch helper utility that will spawn up multiple distributed processes"
+ )
+ )
+
+ # Optional arguments for the launch helper
+ parser.add_argument("--num_cores", type=int, default=1, help="Number of TPU cores to use (1 or 8).")
+
+ # positional
+ parser.add_argument(
+ "training_script",
+ type=str,
+ help=(
+ "The full path to the single TPU training "
+ "program/script to be launched in parallel, "
+ "followed by all the arguments for the "
+ "training script"
+ ),
+ )
+
+ # rest from the training program
+ parser.add_argument("training_script_args", nargs=REMAINDER)
+
+ return parser.parse_args()
+
+
+def main():
+ args = parse_args()
+
+ # Import training_script as a module.
+ script_fpath = Path(args.training_script)
+ sys.path.append(str(script_fpath.parent.resolve()))
+ mod_name = script_fpath.stem
+ mod = importlib.import_module(mod_name)
+
+ # Patch sys.argv
+ sys.argv = [args.training_script] + args.training_script_args + ["--tpu_num_cores", str(args.num_cores)]
+
+ xmp.spawn(mod._mp_fn, args=(), nprocs=args.num_cores)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..b2f5d431f25b5033abdfc777a2e657eb4167d632
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/README.md
@@ -0,0 +1,28 @@
+
+
+# Research projects
+
+This folder contains various research projects using 🤗 Transformers. They are not maintained and require a specific
+version of 🤗 Transformers that is indicated in the requirements file of each folder. Updating them to the most recent version of the library will require some work.
+
+To use any of them, just run the command
+```bash
+pip install -r requirements.txt
+```
+inside the folder of your choice.
+
+If you need help with any of those, contact the author(s), indicated at the top of the `README` of each folder.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/adversarial/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/adversarial/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..3e331a05f4534067ca371ab44832ef4a86dc67f4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/adversarial/README.md
@@ -0,0 +1,38 @@
+## Adversarial evaluation of model performances
+
+Here is an example on evaluating a model using adversarial evaluation of natural language inference with the Heuristic Analysis for NLI Systems (HANS) dataset [McCoy et al., 2019](https://arxiv.org/abs/1902.01007). The example was gracefully provided by [Nafise Sadat Moosavi](https://github.com/ns-moosavi).
+
+The HANS dataset can be downloaded from [this location](https://github.com/tommccoy1/hans).
+
+This is an example of using test_hans.py:
+
+```bash
+export HANS_DIR=path-to-hans
+export MODEL_TYPE=type-of-the-model-e.g.-bert-roberta-xlnet-etc
+export MODEL_PATH=path-to-the-model-directory-that-is-trained-on-NLI-e.g.-by-using-run_glue.py
+
+python run_hans.py \
+ --task_name hans \
+ --model_type $MODEL_TYPE \
+ --do_eval \
+ --data_dir $HANS_DIR \
+ --model_name_or_path $MODEL_PATH \
+ --max_seq_length 128 \
+ --output_dir $MODEL_PATH \
+```
+
+This will create the hans_predictions.txt file in MODEL_PATH, which can then be evaluated using hans/evaluate_heur_output.py from the HANS dataset.
+
+The results of the BERT-base model that is trained on MNLI using batch size 8 and the random seed 42 on the HANS dataset is as follows:
+
+```bash
+Heuristic entailed results:
+lexical_overlap: 0.9702
+subsequence: 0.9942
+constituent: 0.9962
+
+Heuristic non-entailed results:
+lexical_overlap: 0.199
+subsequence: 0.0396
+constituent: 0.118
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/adversarial/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/adversarial/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..99636a7fce1b8ebdd049db2bdeb2248c02791fce
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/adversarial/requirements.txt
@@ -0,0 +1 @@
+transformers == 4.38.0
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/adversarial/run_hans.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/adversarial/run_hans.py
new file mode 100644
index 0000000000000000000000000000000000000000..23625dfa7ee43c8d34afd57c77a4642c14e4a184
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/adversarial/run_hans.py
@@ -0,0 +1,242 @@
+# coding=utf-8
+# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Finetuning the library models for sequence classification on HANS."""
+
+import logging
+import os
+from dataclasses import dataclass, field
+from typing import Dict, List, Optional
+
+import numpy as np
+import torch
+from utils_hans import HansDataset, InputFeatures, hans_processors, hans_tasks_num_labels
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForSequenceClassification,
+ AutoTokenizer,
+ HfArgumentParser,
+ Trainer,
+ TrainingArguments,
+ default_data_collator,
+ set_seed,
+)
+from transformers.trainer_utils import is_main_process
+
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
+ """
+
+ model_name_or_path: str = field(
+ metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None,
+ metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ task_name: str = field(
+ metadata={"help": "The name of the task to train selected in the list: " + ", ".join(hans_processors.keys())}
+ )
+ data_dir: str = field(
+ metadata={"help": "The input data dir. Should contain the .tsv files (or other data files) for the task."}
+ )
+ max_seq_length: int = field(
+ default=128,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+
+
+def hans_data_collator(features: List[InputFeatures]) -> Dict[str, torch.Tensor]:
+ """
+ Data collator that removes the "pairID" key if present.
+ """
+ batch = default_data_collator(features)
+ _ = batch.pop("pairID", None)
+ return batch
+
+
+def main():
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ if (
+ os.path.exists(training_args.output_dir)
+ and os.listdir(training_args.output_dir)
+ and training_args.do_train
+ and not training_args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. Use"
+ " --overwrite_output_dir to overcome."
+ )
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO if training_args.local_rank in [-1, 0] else logging.WARN,
+ )
+ logger.warning(
+ "Process rank: %s, device: %s, n_gpu: %s, distributed training: %s, 16-bits training: %s",
+ training_args.local_rank,
+ training_args.device,
+ training_args.n_gpu,
+ bool(training_args.local_rank != -1),
+ training_args.fp16,
+ )
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ if is_main_process(training_args.local_rank):
+ transformers.utils.logging.set_verbosity_info()
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+ logger.info("Training/evaluation parameters %s", training_args)
+
+ # Set seed
+ set_seed(training_args.seed)
+
+ try:
+ num_labels = hans_tasks_num_labels[data_args.task_name]
+ except KeyError:
+ raise ValueError("Task not found: %s" % (data_args.task_name))
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+
+ config = AutoConfig.from_pretrained(
+ model_args.config_name if model_args.config_name else model_args.model_name_or_path,
+ num_labels=num_labels,
+ finetuning_task=data_args.task_name,
+ cache_dir=model_args.cache_dir,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
+ cache_dir=model_args.cache_dir,
+ )
+ model = AutoModelForSequenceClassification.from_pretrained(
+ model_args.model_name_or_path,
+ from_tf=bool(".ckpt" in model_args.model_name_or_path),
+ config=config,
+ cache_dir=model_args.cache_dir,
+ )
+
+ # Get datasets
+ train_dataset = (
+ HansDataset(
+ data_dir=data_args.data_dir,
+ tokenizer=tokenizer,
+ task=data_args.task_name,
+ max_seq_length=data_args.max_seq_length,
+ overwrite_cache=data_args.overwrite_cache,
+ )
+ if training_args.do_train
+ else None
+ )
+ eval_dataset = (
+ HansDataset(
+ data_dir=data_args.data_dir,
+ tokenizer=tokenizer,
+ task=data_args.task_name,
+ max_seq_length=data_args.max_seq_length,
+ overwrite_cache=data_args.overwrite_cache,
+ evaluate=True,
+ )
+ if training_args.do_eval
+ else None
+ )
+
+ # Initialize our Trainer
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_dataset,
+ eval_dataset=eval_dataset,
+ data_collator=hans_data_collator,
+ )
+
+ # Training
+ if training_args.do_train:
+ trainer.train(
+ model_path=model_args.model_name_or_path if os.path.isdir(model_args.model_name_or_path) else None
+ )
+ trainer.save_model()
+ # For convenience, we also re-save the tokenizer to the same directory,
+ # so that you can share your model easily on huggingface.co/models =)
+ if trainer.is_world_master():
+ tokenizer.save_pretrained(training_args.output_dir)
+
+ # Evaluation
+ if training_args.do_eval:
+ logger.info("*** Evaluate ***")
+
+ output = trainer.predict(eval_dataset)
+ preds = output.predictions
+ preds = np.argmax(preds, axis=1)
+
+ pair_ids = [ex.pairID for ex in eval_dataset]
+ output_eval_file = os.path.join(training_args.output_dir, "hans_predictions.txt")
+ label_list = eval_dataset.get_labels()
+ if trainer.is_world_master():
+ with open(output_eval_file, "w") as writer:
+ writer.write("pairID,gold_label\n")
+ for pid, pred in zip(pair_ids, preds):
+ writer.write("ex" + str(pid) + "," + label_list[int(pred)] + "\n")
+
+ trainer._log(output.metrics)
+
+
+def _mp_fn(index):
+ # For xla_spawn (TPUs)
+ main()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/adversarial/utils_hans.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/adversarial/utils_hans.py
new file mode 100644
index 0000000000000000000000000000000000000000..f051e60f84fefdb54ee991a1668d14528da28ac0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/adversarial/utils_hans.py
@@ -0,0 +1,339 @@
+# coding=utf-8
+# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import logging
+import os
+from dataclasses import dataclass
+from typing import List, Optional, Union
+
+import tqdm
+from filelock import FileLock
+
+from transformers import (
+ BartTokenizer,
+ BartTokenizerFast,
+ DataProcessor,
+ PreTrainedTokenizer,
+ RobertaTokenizer,
+ RobertaTokenizerFast,
+ XLMRobertaTokenizer,
+ is_tf_available,
+ is_torch_available,
+)
+
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass(frozen=True)
+class InputExample:
+ """
+ A single training/test example for simple sequence classification.
+
+ Args:
+ guid: Unique id for the example.
+ text_a: string. The untokenized text of the first sequence. For single
+ sequence tasks, only this sequence must be specified.
+ text_b: (Optional) string. The untokenized text of the second sequence.
+ Only must be specified for sequence pair tasks.
+ label: (Optional) string. The label of the example. This should be
+ specified for train and dev examples, but not for test examples.
+ pairID: (Optional) string. Unique identifier for the pair of sentences.
+ """
+
+ guid: str
+ text_a: str
+ text_b: Optional[str] = None
+ label: Optional[str] = None
+ pairID: Optional[str] = None
+
+
+@dataclass(frozen=True)
+class InputFeatures:
+ """
+ A single set of features of data.
+ Property names are the same names as the corresponding inputs to a model.
+
+ Args:
+ input_ids: Indices of input sequence tokens in the vocabulary.
+ attention_mask: Mask to avoid performing attention on padding token indices.
+ Mask values selected in ``[0, 1]``:
+ Usually ``1`` for tokens that are NOT MASKED, ``0`` for MASKED (padded) tokens.
+ token_type_ids: (Optional) Segment token indices to indicate first and second
+ portions of the inputs. Only some models use them.
+ label: (Optional) Label corresponding to the input. Int for classification problems,
+ float for regression problems.
+ pairID: (Optional) Unique identifier for the pair of sentences.
+ """
+
+ input_ids: List[int]
+ attention_mask: Optional[List[int]] = None
+ token_type_ids: Optional[List[int]] = None
+ label: Optional[Union[int, float]] = None
+ pairID: Optional[int] = None
+
+
+if is_torch_available():
+ import torch
+ from torch.utils.data import Dataset
+
+ class HansDataset(Dataset):
+ """
+ This will be superseded by a framework-agnostic approach
+ soon.
+ """
+
+ features: List[InputFeatures]
+
+ def __init__(
+ self,
+ data_dir: str,
+ tokenizer: PreTrainedTokenizer,
+ task: str,
+ max_seq_length: Optional[int] = None,
+ overwrite_cache=False,
+ evaluate: bool = False,
+ ):
+ processor = hans_processors[task]()
+
+ cached_features_file = os.path.join(
+ data_dir,
+ "cached_{}_{}_{}_{}".format(
+ "dev" if evaluate else "train",
+ tokenizer.__class__.__name__,
+ str(max_seq_length),
+ task,
+ ),
+ )
+ label_list = processor.get_labels()
+ if tokenizer.__class__ in (
+ RobertaTokenizer,
+ RobertaTokenizerFast,
+ XLMRobertaTokenizer,
+ BartTokenizer,
+ BartTokenizerFast,
+ ):
+ # HACK(label indices are swapped in RoBERTa pretrained model)
+ label_list[1], label_list[2] = label_list[2], label_list[1]
+ self.label_list = label_list
+
+ # Make sure only the first process in distributed training processes the dataset,
+ # and the others will use the cache.
+ lock_path = cached_features_file + ".lock"
+ with FileLock(lock_path):
+ if os.path.exists(cached_features_file) and not overwrite_cache:
+ logger.info(f"Loading features from cached file {cached_features_file}")
+ self.features = torch.load(cached_features_file)
+ else:
+ logger.info(f"Creating features from dataset file at {data_dir}")
+
+ examples = (
+ processor.get_dev_examples(data_dir) if evaluate else processor.get_train_examples(data_dir)
+ )
+
+ logger.info("Training examples: %s", len(examples))
+ self.features = hans_convert_examples_to_features(examples, label_list, max_seq_length, tokenizer)
+ logger.info("Saving features into cached file %s", cached_features_file)
+ torch.save(self.features, cached_features_file)
+
+ def __len__(self):
+ return len(self.features)
+
+ def __getitem__(self, i) -> InputFeatures:
+ return self.features[i]
+
+ def get_labels(self):
+ return self.label_list
+
+
+if is_tf_available():
+ import tensorflow as tf
+
+ class TFHansDataset:
+ """
+ This will be superseded by a framework-agnostic approach
+ soon.
+ """
+
+ features: List[InputFeatures]
+
+ def __init__(
+ self,
+ data_dir: str,
+ tokenizer: PreTrainedTokenizer,
+ task: str,
+ max_seq_length: Optional[int] = 128,
+ overwrite_cache=False,
+ evaluate: bool = False,
+ ):
+ processor = hans_processors[task]()
+ label_list = processor.get_labels()
+ if tokenizer.__class__ in (
+ RobertaTokenizer,
+ RobertaTokenizerFast,
+ XLMRobertaTokenizer,
+ BartTokenizer,
+ BartTokenizerFast,
+ ):
+ # HACK(label indices are swapped in RoBERTa pretrained model)
+ label_list[1], label_list[2] = label_list[2], label_list[1]
+ self.label_list = label_list
+
+ examples = processor.get_dev_examples(data_dir) if evaluate else processor.get_train_examples(data_dir)
+ self.features = hans_convert_examples_to_features(examples, label_list, max_seq_length, tokenizer)
+
+ def gen():
+ for ex_index, ex in tqdm.tqdm(enumerate(self.features), desc="convert examples to features"):
+ if ex_index % 10000 == 0:
+ logger.info("Writing example %d of %d" % (ex_index, len(examples)))
+
+ yield (
+ {
+ "example_id": 0,
+ "input_ids": ex.input_ids,
+ "attention_mask": ex.attention_mask,
+ "token_type_ids": ex.token_type_ids,
+ },
+ ex.label,
+ )
+
+ self.dataset = tf.data.Dataset.from_generator(
+ gen,
+ (
+ {
+ "example_id": tf.int32,
+ "input_ids": tf.int32,
+ "attention_mask": tf.int32,
+ "token_type_ids": tf.int32,
+ },
+ tf.int64,
+ ),
+ (
+ {
+ "example_id": tf.TensorShape([]),
+ "input_ids": tf.TensorShape([None, None]),
+ "attention_mask": tf.TensorShape([None, None]),
+ "token_type_ids": tf.TensorShape([None, None]),
+ },
+ tf.TensorShape([]),
+ ),
+ )
+
+ def get_dataset(self):
+ return self.dataset
+
+ def __len__(self):
+ return len(self.features)
+
+ def __getitem__(self, i) -> InputFeatures:
+ return self.features[i]
+
+ def get_labels(self):
+ return self.label_list
+
+
+class HansProcessor(DataProcessor):
+ """Processor for the HANS data set."""
+
+ def get_train_examples(self, data_dir):
+ """See base class."""
+ return self._create_examples(self._read_tsv(os.path.join(data_dir, "heuristics_train_set.txt")), "train")
+
+ def get_dev_examples(self, data_dir):
+ """See base class."""
+ return self._create_examples(self._read_tsv(os.path.join(data_dir, "heuristics_evaluation_set.txt")), "dev")
+
+ def get_labels(self):
+ """See base class.
+ Note that we follow the standard three labels for MNLI
+ (see :class:`~transformers.data.processors.utils.MnliProcessor`)
+ but the HANS evaluation groups `contradiction` and `neutral` into `non-entailment` (label 0) while
+ `entailment` is label 1."""
+ return ["contradiction", "entailment", "neutral"]
+
+ def _create_examples(self, lines, set_type):
+ """Creates examples for the training and dev sets."""
+ examples = []
+ for i, line in enumerate(lines):
+ if i == 0:
+ continue
+ guid = "%s-%s" % (set_type, line[0])
+ text_a = line[5]
+ text_b = line[6]
+ pairID = line[7][2:] if line[7].startswith("ex") else line[7]
+ label = line[0]
+ examples.append(InputExample(guid=guid, text_a=text_a, text_b=text_b, label=label, pairID=pairID))
+ return examples
+
+
+def hans_convert_examples_to_features(
+ examples: List[InputExample],
+ label_list: List[str],
+ max_length: int,
+ tokenizer: PreTrainedTokenizer,
+):
+ """
+ Loads a data file into a list of ``InputFeatures``
+
+ Args:
+ examples: List of ``InputExamples`` containing the examples.
+ label_list: List of labels. Can be obtained from the processor using the ``processor.get_labels()`` method.
+ max_length: Maximum example length.
+ tokenizer: Instance of a tokenizer that will tokenize the examples.
+
+ Returns:
+ A list of task-specific ``InputFeatures`` which can be fed to the model.
+
+ """
+
+ label_map = {label: i for i, label in enumerate(label_list)}
+
+ features = []
+ for ex_index, example in tqdm.tqdm(enumerate(examples), desc="convert examples to features"):
+ if ex_index % 10000 == 0:
+ logger.info("Writing example %d" % (ex_index))
+
+ inputs = tokenizer(
+ example.text_a,
+ example.text_b,
+ add_special_tokens=True,
+ max_length=max_length,
+ padding="max_length",
+ truncation=True,
+ return_overflowing_tokens=True,
+ )
+
+ label = label_map[example.label] if example.label in label_map else 0
+
+ pairID = int(example.pairID)
+
+ features.append(InputFeatures(**inputs, label=label, pairID=pairID))
+
+ for i, example in enumerate(examples[:5]):
+ logger.info("*** Example ***")
+ logger.info(f"guid: {example}")
+ logger.info(f"features: {features[i]}")
+
+ return features
+
+
+hans_tasks_num_labels = {
+ "hans": 3,
+}
+
+hans_processors = {
+ "hans": HansProcessor,
+}
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..b405e8a94887504d6debbea6051ff4e976740f25
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/README.md
@@ -0,0 +1,89 @@
+# Patience-based Early Exit
+
+Patience-based Early Exit (PABEE) is a plug-and-play inference method for pretrained language models.
+We have already implemented it on BERT and ALBERT. Basically, you can make your LM faster and more robust with PABEE. It can even improve the performance of ALBERT on GLUE. The only sacrifice is that the batch size can only be 1.
+Learn more in the paper ["BERT Loses Patience: Fast and Robust Inference with Early Exit"](https://arxiv.org/abs/2006.04152) and the official [GitHub repo](https://github.com/JetRunner/PABEE).
+
+
+
+## Training
+
+You can fine-tune a pretrained language model (you can choose from BERT and ALBERT) and train the internal classifiers by:
+```bash
+export GLUE_DIR=/path/to/glue_data
+export TASK_NAME=MRPC
+
+python ./run_glue_with_pabee.py \
+ --model_type albert \
+ --model_name_or_path google-bert/bert-base-uncased/albert/albert-base-v2 \
+ --task_name $TASK_NAME \
+ --do_train \
+ --do_eval \
+ --do_lower_case \
+ --data_dir "$GLUE_DIR/$TASK_NAME" \
+ --max_seq_length 128 \
+ --per_gpu_train_batch_size 32 \
+ --per_gpu_eval_batch_size 32 \
+ --learning_rate 2e-5 \
+ --save_steps 50 \
+ --logging_steps 50 \
+ --num_train_epochs 5 \
+ --output_dir /path/to/save/ \
+ --evaluate_during_training
+```
+
+## Inference
+
+You can inference with different patience settings by:
+```bash
+export GLUE_DIR=/path/to/glue_data
+export TASK_NAME=MRPC
+
+python ./run_glue_with_pabee.py \
+ --model_type albert \
+ --model_name_or_path /path/to/save/ \
+ --task_name $TASK_NAME \
+ --do_eval \
+ --do_lower_case \
+ --data_dir "$GLUE_DIR/$TASK_NAME" \
+ --max_seq_length 128 \
+ --per_gpu_eval_batch_size 1 \
+ --learning_rate 2e-5 \
+ --logging_steps 50 \
+ --num_train_epochs 15 \
+ --output_dir /path/to/save/ \
+ --eval_all_checkpoints \
+ --patience 3,4,5,6,7,8
+```
+where `patience` can be a list of patience settings, separated by a comma. It will help determine which patience works best.
+
+When evaluating on a regression task (STS-B), you may add `--regression_threshold 0.1` to define the regression threshold.
+
+## Results
+On the GLUE dev set:
+
+| Model | \#Param | Speed | CoLA | MNLI | MRPC | QNLI | QQP | RTE | SST\-2 | STS\-B |
+|--------------|---------|--------|-------|-------|-------|-------|-------|-------|--------|--------|
+| ALBERT\-base | 12M | | 58\.9 | 84\.6 | 89\.5 | 91\.7 | 89\.6 | 78\.6 | 92\.8 | 89\.5 |
+| \+PABEE | 12M | 1\.57x | 61\.2 | 85\.1 | 90\.0 | 91\.8 | 89\.6 | 80\.1 | 93\.0 | 90\.1 |
+
+| Model | \#Param | Speed\-up | MNLI | SST\-2 | STS\-B |
+|---------------|---------|-----------|-------|--------|--------|
+| BERT\-base | 108M | | 84\.5 | 92\.1 | 88\.9 |
+| \+PABEE | 108M | 1\.62x | 83\.6 | 92\.0 | 88\.7 |
+| ALBERT\-large | 18M | | 86\.4 | 94\.9 | 90\.4 |
+| \+PABEE | 18M | 2\.42x | 86\.8 | 95\.2 | 90\.6 |
+
+
+## Citation
+If you find this resource useful, please consider citing the following paper:
+```bibtex
+@misc{zhou2020bert,
+ title={BERT Loses Patience: Fast and Robust Inference with Early Exit},
+ author={Wangchunshu Zhou and Canwen Xu and Tao Ge and Julian McAuley and Ke Xu and Furu Wei},
+ year={2020},
+ eprint={2006.04152},
+ archivePrefix={arXiv},
+ primaryClass={cs.CL}
+}
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/pabee/__init__.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/pabee/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/pabee/modeling_pabee_albert.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/pabee/modeling_pabee_albert.py
new file mode 100644
index 0000000000000000000000000000000000000000..5b30155a736a964da6f7ac4181498d304b05bba4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/pabee/modeling_pabee_albert.py
@@ -0,0 +1,320 @@
+# coding=utf-8
+# Copyright 2020 Google AI, Google Brain, the HuggingFace Inc. team and Microsoft Corporation.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch ALBERT model with Patience-based Early Exit."""
+
+import logging
+
+import torch
+from torch import nn
+from torch.nn import CrossEntropyLoss, MSELoss
+
+from transformers.file_utils import add_start_docstrings, add_start_docstrings_to_model_forward
+from transformers.models.albert.modeling_albert import (
+ ALBERT_INPUTS_DOCSTRING,
+ ALBERT_START_DOCSTRING,
+ AlbertModel,
+ AlbertPreTrainedModel,
+ AlbertTransformer,
+)
+
+
+logger = logging.getLogger(__name__)
+
+
+class AlbertTransformerWithPabee(AlbertTransformer):
+ def adaptive_forward(self, hidden_states, current_layer, attention_mask=None, head_mask=None):
+ if current_layer == 0:
+ hidden_states = self.embedding_hidden_mapping_in(hidden_states)
+ else:
+ hidden_states = hidden_states[0]
+
+ layers_per_group = int(self.config.num_hidden_layers / self.config.num_hidden_groups)
+
+ # Index of the hidden group
+ group_idx = int(current_layer / (self.config.num_hidden_layers / self.config.num_hidden_groups))
+
+ layer_group_output = self.albert_layer_groups[group_idx](
+ hidden_states,
+ attention_mask,
+ head_mask[group_idx * layers_per_group : (group_idx + 1) * layers_per_group],
+ )
+ hidden_states = layer_group_output[0]
+
+ return (hidden_states,)
+
+
+@add_start_docstrings(
+ "The bare ALBERT Model transformer with PABEE outputting raw hidden-states without any specific head on top.",
+ ALBERT_START_DOCSTRING,
+)
+class AlbertModelWithPabee(AlbertModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.encoder = AlbertTransformerWithPabee(config)
+
+ self.init_weights()
+ self.patience = 0
+ self.inference_instances_num = 0
+ self.inference_layers_num = 0
+
+ self.regression_threshold = 0
+
+ def set_regression_threshold(self, threshold):
+ self.regression_threshold = threshold
+
+ def set_patience(self, patience):
+ self.patience = patience
+
+ def reset_stats(self):
+ self.inference_instances_num = 0
+ self.inference_layers_num = 0
+
+ def log_stats(self):
+ avg_inf_layers = self.inference_layers_num / self.inference_instances_num
+ message = (
+ f"*** Patience = {self.patience} Avg. Inference Layers = {avg_inf_layers:.2f} Speed Up ="
+ f" {1 - avg_inf_layers / self.config.num_hidden_layers:.2f} ***"
+ )
+ print(message)
+
+ @add_start_docstrings_to_model_forward(ALBERT_INPUTS_DOCSTRING)
+ def forward(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ token_type_ids=None,
+ position_ids=None,
+ head_mask=None,
+ inputs_embeds=None,
+ output_dropout=None,
+ output_layers=None,
+ regression=False,
+ ):
+ r"""
+ Return:
+ :obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.AlbertConfig`) and inputs:
+ last_hidden_state (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`):
+ Sequence of hidden-states at the output of the last layer of the model.
+ pooler_output (:obj:`torch.FloatTensor`: of shape :obj:`(batch_size, hidden_size)`):
+ Last layer hidden-state of the first token of the sequence (classification token)
+ further processed by a Linear layer and a Tanh activation function. The Linear
+ layer weights are trained from the next sentence prediction (classification)
+ objective during pre-training.
+
+ This output is usually *not* a good summary
+ of the semantic content of the input, you're often better with averaging or pooling
+ the sequence of hidden-states for the whole input sequence.
+ hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_hidden_states=True``):
+ Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
+ of shape :obj:`(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_attentions=True``):
+ Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape
+ :obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ """
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ input_shape = input_ids.size()
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ if attention_mask is None:
+ attention_mask = torch.ones(input_shape, device=device)
+ if token_type_ids is None:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=device)
+
+ extended_attention_mask = attention_mask.unsqueeze(1).unsqueeze(2)
+ extended_attention_mask = extended_attention_mask.to(dtype=self.dtype) # fp16 compatibility
+ extended_attention_mask = (1.0 - extended_attention_mask) * -10000.0
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output = self.embeddings(
+ input_ids, position_ids=position_ids, token_type_ids=token_type_ids, inputs_embeds=inputs_embeds
+ )
+ encoder_outputs = embedding_output
+
+ if self.training:
+ res = []
+ for i in range(self.config.num_hidden_layers):
+ encoder_outputs = self.encoder.adaptive_forward(
+ encoder_outputs,
+ current_layer=i,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ )
+
+ pooled_output = self.pooler_activation(self.pooler(encoder_outputs[0][:, 0]))
+ logits = output_layers[i](output_dropout(pooled_output))
+ res.append(logits)
+ elif self.patience == 0: # Use all layers for inference
+ encoder_outputs = self.encoder(encoder_outputs, extended_attention_mask, head_mask=head_mask)
+ pooled_output = self.pooler_activation(self.pooler(encoder_outputs[0][:, 0]))
+ res = [output_layers[self.config.num_hidden_layers - 1](pooled_output)]
+ else:
+ patient_counter = 0
+ patient_result = None
+ calculated_layer_num = 0
+ for i in range(self.config.num_hidden_layers):
+ calculated_layer_num += 1
+ encoder_outputs = self.encoder.adaptive_forward(
+ encoder_outputs,
+ current_layer=i,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ )
+
+ pooled_output = self.pooler_activation(self.pooler(encoder_outputs[0][:, 0]))
+ logits = output_layers[i](pooled_output)
+ if regression:
+ labels = logits.detach()
+ if patient_result is not None:
+ patient_labels = patient_result.detach()
+ if (patient_result is not None) and torch.abs(patient_result - labels) < self.regression_threshold:
+ patient_counter += 1
+ else:
+ patient_counter = 0
+ else:
+ labels = logits.detach().argmax(dim=1)
+ if patient_result is not None:
+ patient_labels = patient_result.detach().argmax(dim=1)
+ if (patient_result is not None) and torch.all(labels.eq(patient_labels)):
+ patient_counter += 1
+ else:
+ patient_counter = 0
+
+ patient_result = logits
+ if patient_counter == self.patience:
+ break
+ res = [patient_result]
+ self.inference_layers_num += calculated_layer_num
+ self.inference_instances_num += 1
+
+ return res
+
+
+@add_start_docstrings(
+ """Albert Model transformer with PABEE and a sequence classification/regression head on top (a linear layer on top of
+ the pooled output) e.g. for GLUE tasks. """,
+ ALBERT_START_DOCSTRING,
+)
+class AlbertForSequenceClassificationWithPabee(AlbertPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.albert = AlbertModelWithPabee(config)
+ self.dropout = nn.Dropout(config.classifier_dropout_prob)
+ self.classifiers = nn.ModuleList(
+ [nn.Linear(config.hidden_size, self.config.num_labels) for _ in range(config.num_hidden_layers)]
+ )
+
+ self.init_weights()
+
+ @add_start_docstrings_to_model_forward(ALBERT_INPUTS_DOCSTRING)
+ def forward(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ token_type_ids=None,
+ position_ids=None,
+ head_mask=None,
+ inputs_embeds=None,
+ labels=None,
+ ):
+ r"""
+ labels (:obj:`torch.LongTensor` of shape :obj:`(batch_size,)`, `optional`):
+ Labels for computing the sequence classification/regression loss.
+ Indices should be in ``[0, ..., config.num_labels - 1]``.
+ If ``config.num_labels == 1`` a regression loss is computed (Mean-Square loss),
+ If ``config.num_labels > 1`` a classification loss is computed (Cross-Entropy).
+
+ Returns:
+ :obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.AlbertConfig`) and inputs:
+ loss (`optional`, returned when ``labels`` is provided) ``torch.FloatTensor`` of shape ``(1,)``:
+ Classification (or regression if config.num_labels==1) loss.
+ logits ``torch.FloatTensor`` of shape ``(batch_size, config.num_labels)``
+ Classification (or regression if config.num_labels==1) scores (before SoftMax).
+ hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_hidden_states=True``):
+ Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
+ of shape :obj:`(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_attentions=True``):
+ Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape
+ :obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+
+ Examples::
+
+ from transformers import AlbertTokenizer
+ from pabee import AlbertForSequenceClassificationWithPabee
+ from torch import nn
+ import torch
+
+ tokenizer = AlbertTokenizer.from_pretrained('albert/albert-base-v2')
+ model = AlbertForSequenceClassificationWithPabee.from_pretrained('albert/albert-base-v2')
+ input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute")).unsqueeze(0) # Batch size 1
+ labels = torch.tensor([1]).unsqueeze(0) # Batch size 1
+ outputs = model(input_ids, labels=labels)
+ loss, logits = outputs[:2]
+
+ """
+
+ logits = self.albert(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_dropout=self.dropout,
+ output_layers=self.classifiers,
+ regression=self.num_labels == 1,
+ )
+
+ outputs = (logits[-1],)
+
+ if labels is not None:
+ total_loss = None
+ total_weights = 0
+ for ix, logits_item in enumerate(logits):
+ if self.num_labels == 1:
+ # We are doing regression
+ loss_fct = MSELoss()
+ loss = loss_fct(logits_item.view(-1), labels.view(-1))
+ else:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits_item.view(-1, self.num_labels), labels.view(-1))
+ if total_loss is None:
+ total_loss = loss
+ else:
+ total_loss += loss * (ix + 1)
+ total_weights += ix + 1
+ outputs = (total_loss / total_weights,) + outputs
+
+ return outputs
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/pabee/modeling_pabee_bert.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/pabee/modeling_pabee_bert.py
new file mode 100644
index 0000000000000000000000000000000000000000..c1ce924a57a2972ba2e7766ce2827010a5699fd0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/pabee/modeling_pabee_bert.py
@@ -0,0 +1,345 @@
+# coding=utf-8
+# Copyright 2020 The Google AI Language Team Authors, The HuggingFace Inc. team and Microsoft Corporation.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch BERT model with Patience-based Early Exit."""
+
+import logging
+
+import torch
+from torch import nn
+from torch.nn import CrossEntropyLoss, MSELoss
+
+from transformers.file_utils import add_start_docstrings, add_start_docstrings_to_model_forward
+from transformers.models.bert.modeling_bert import (
+ BERT_INPUTS_DOCSTRING,
+ BERT_START_DOCSTRING,
+ BertEncoder,
+ BertModel,
+ BertPreTrainedModel,
+)
+
+
+logger = logging.getLogger(__name__)
+
+
+class BertEncoderWithPabee(BertEncoder):
+ def adaptive_forward(self, hidden_states, current_layer, attention_mask=None, head_mask=None):
+ layer_outputs = self.layer[current_layer](hidden_states, attention_mask, head_mask[current_layer])
+
+ hidden_states = layer_outputs[0]
+
+ return hidden_states
+
+
+@add_start_docstrings(
+ "The bare Bert Model transformer with PABEE outputting raw hidden-states without any specific head on top.",
+ BERT_START_DOCSTRING,
+)
+class BertModelWithPabee(BertModel):
+ """
+
+ The model can behave as an encoder (with only self-attention) as well
+ as a decoder, in which case a layer of cross-attention is added between
+ the self-attention layers, following the architecture described in `Attention is all you need`_ by Ashish Vaswani,
+ Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Lukasz Kaiser and Illia Polosukhin.
+
+ To behave as a decoder the model needs to be initialized with the
+ :obj:`is_decoder` argument of the configuration set to :obj:`True`; an
+ :obj:`encoder_hidden_states` is expected as an input to the forward pass.
+
+ .. _`Attention is all you need`:
+ https://arxiv.org/abs/1706.03762
+
+ """
+
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.encoder = BertEncoderWithPabee(config)
+
+ self.init_weights()
+ self.patience = 0
+ self.inference_instances_num = 0
+ self.inference_layers_num = 0
+
+ self.regression_threshold = 0
+
+ def set_regression_threshold(self, threshold):
+ self.regression_threshold = threshold
+
+ def set_patience(self, patience):
+ self.patience = patience
+
+ def reset_stats(self):
+ self.inference_instances_num = 0
+ self.inference_layers_num = 0
+
+ def log_stats(self):
+ avg_inf_layers = self.inference_layers_num / self.inference_instances_num
+ message = (
+ f"*** Patience = {self.patience} Avg. Inference Layers = {avg_inf_layers:.2f} Speed Up ="
+ f" {1 - avg_inf_layers / self.config.num_hidden_layers:.2f} ***"
+ )
+ print(message)
+
+ @add_start_docstrings_to_model_forward(BERT_INPUTS_DOCSTRING)
+ def forward(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ token_type_ids=None,
+ position_ids=None,
+ head_mask=None,
+ inputs_embeds=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ output_dropout=None,
+ output_layers=None,
+ regression=False,
+ ):
+ r"""
+ Return:
+ :obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.BertConfig`) and inputs:
+ last_hidden_state (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`):
+ Sequence of hidden-states at the output of the last layer of the model.
+ pooler_output (:obj:`torch.FloatTensor`: of shape :obj:`(batch_size, hidden_size)`):
+ Last layer hidden-state of the first token of the sequence (classification token)
+ further processed by a Linear layer and a Tanh activation function. The Linear
+ layer weights are trained from the next sentence prediction (classification)
+ objective during pre-training.
+
+ This output is usually *not* a good summary
+ of the semantic content of the input, you're often better with averaging or pooling
+ the sequence of hidden-states for the whole input sequence.
+ hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_hidden_states=True``):
+ Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
+ of shape :obj:`(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_attentions=True``):
+ Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape
+ :obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ """
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ input_shape = input_ids.size()
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ if attention_mask is None:
+ attention_mask = torch.ones(input_shape, device=device)
+ if token_type_ids is None:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=device)
+
+ # We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length]
+ # ourselves in which case we just need to make it broadcastable to all heads.
+ extended_attention_mask: torch.Tensor = self.get_extended_attention_mask(attention_mask, input_shape, device)
+
+ # If a 2D ou 3D attention mask is provided for the cross-attention
+ # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length]
+ if self.config.is_decoder and encoder_hidden_states is not None:
+ encoder_batch_size, encoder_sequence_length, _ = encoder_hidden_states.size()
+ encoder_hidden_shape = (encoder_batch_size, encoder_sequence_length)
+ if encoder_attention_mask is None:
+ encoder_attention_mask = torch.ones(encoder_hidden_shape, device=device)
+ encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask)
+ else:
+ encoder_extended_attention_mask = None
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output = self.embeddings(
+ input_ids=input_ids, position_ids=position_ids, token_type_ids=token_type_ids, inputs_embeds=inputs_embeds
+ )
+ encoder_outputs = embedding_output
+
+ if self.training:
+ res = []
+ for i in range(self.config.num_hidden_layers):
+ encoder_outputs = self.encoder.adaptive_forward(
+ encoder_outputs, current_layer=i, attention_mask=extended_attention_mask, head_mask=head_mask
+ )
+
+ pooled_output = self.pooler(encoder_outputs)
+ logits = output_layers[i](output_dropout(pooled_output))
+ res.append(logits)
+ elif self.patience == 0: # Use all layers for inference
+ encoder_outputs = self.encoder(
+ embedding_output,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_extended_attention_mask,
+ )
+ pooled_output = self.pooler(encoder_outputs[0])
+ res = [output_layers[self.config.num_hidden_layers - 1](pooled_output)]
+ else:
+ patient_counter = 0
+ patient_result = None
+ calculated_layer_num = 0
+ for i in range(self.config.num_hidden_layers):
+ calculated_layer_num += 1
+ encoder_outputs = self.encoder.adaptive_forward(
+ encoder_outputs, current_layer=i, attention_mask=extended_attention_mask, head_mask=head_mask
+ )
+
+ pooled_output = self.pooler(encoder_outputs)
+ logits = output_layers[i](pooled_output)
+ if regression:
+ labels = logits.detach()
+ if patient_result is not None:
+ patient_labels = patient_result.detach()
+ if (patient_result is not None) and torch.abs(patient_result - labels) < self.regression_threshold:
+ patient_counter += 1
+ else:
+ patient_counter = 0
+ else:
+ labels = logits.detach().argmax(dim=1)
+ if patient_result is not None:
+ patient_labels = patient_result.detach().argmax(dim=1)
+ if (patient_result is not None) and torch.all(labels.eq(patient_labels)):
+ patient_counter += 1
+ else:
+ patient_counter = 0
+
+ patient_result = logits
+ if patient_counter == self.patience:
+ break
+ res = [patient_result]
+ self.inference_layers_num += calculated_layer_num
+ self.inference_instances_num += 1
+
+ return res
+
+
+@add_start_docstrings(
+ """Bert Model transformer with PABEE and a sequence classification/regression head on top (a linear layer on top of
+ the pooled output) e.g. for GLUE tasks. """,
+ BERT_START_DOCSTRING,
+)
+class BertForSequenceClassificationWithPabee(BertPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.bert = BertModelWithPabee(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.classifiers = nn.ModuleList(
+ [nn.Linear(config.hidden_size, self.config.num_labels) for _ in range(config.num_hidden_layers)]
+ )
+
+ self.init_weights()
+
+ @add_start_docstrings_to_model_forward(BERT_INPUTS_DOCSTRING)
+ def forward(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ token_type_ids=None,
+ position_ids=None,
+ head_mask=None,
+ inputs_embeds=None,
+ labels=None,
+ ):
+ r"""
+ labels (:obj:`torch.LongTensor` of shape :obj:`(batch_size,)`, `optional`):
+ Labels for computing the sequence classification/regression loss.
+ Indices should be in :obj:`[0, ..., config.num_labels - 1]`.
+ If :obj:`config.num_labels == 1` a regression loss is computed (Mean-Square loss),
+ If :obj:`config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+
+ Returns:
+ :obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.BertConfig`) and inputs:
+ loss (:obj:`torch.FloatTensor` of shape :obj:`(1,)`, `optional`, returned when :obj:`label` is provided):
+ Classification (or regression if config.num_labels==1) loss.
+ logits (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, config.num_labels)`):
+ Classification (or regression if config.num_labels==1) scores (before SoftMax).
+ hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_hidden_states=True``):
+ Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
+ of shape :obj:`(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_attentions=True``):
+ Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape
+ :obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+
+ Examples::
+
+ from transformers import BertTokenizer, BertForSequenceClassification
+ from pabee import BertForSequenceClassificationWithPabee
+ from torch import nn
+ import torch
+
+ tokenizer = BertTokenizer.from_pretrained('google-bert/bert-base-uncased')
+ model = BertForSequenceClassificationWithPabee.from_pretrained('google-bert/bert-base-uncased')
+
+ input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True)).unsqueeze(0) # Batch size 1
+ labels = torch.tensor([1]).unsqueeze(0) # Batch size 1
+ outputs = model(input_ids, labels=labels)
+
+ loss, logits = outputs[:2]
+
+ """
+
+ logits = self.bert(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_dropout=self.dropout,
+ output_layers=self.classifiers,
+ regression=self.num_labels == 1,
+ )
+
+ outputs = (logits[-1],)
+
+ if labels is not None:
+ total_loss = None
+ total_weights = 0
+ for ix, logits_item in enumerate(logits):
+ if self.num_labels == 1:
+ # We are doing regression
+ loss_fct = MSELoss()
+ loss = loss_fct(logits_item.view(-1), labels.view(-1))
+ else:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits_item.view(-1, self.num_labels), labels.view(-1))
+ if total_loss is None:
+ total_loss = loss
+ else:
+ total_loss += loss * (ix + 1)
+ total_weights += ix + 1
+ outputs = (total_loss / total_weights,) + outputs
+
+ return outputs
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..af3b01e0645d7996ce1e1d04e7723f9c7b02d2b5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/requirements.txt
@@ -0,0 +1 @@
+transformers == 4.38.0
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/run_glue_with_pabee.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/run_glue_with_pabee.py
new file mode 100644
index 0000000000000000000000000000000000000000..d1ee5ddde3c6cab9a4fedebf7262711ec0fda44b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/run_glue_with_pabee.py
@@ -0,0 +1,751 @@
+# coding=utf-8
+# Copyright 2020 The Google AI Language Team Authors, The HuggingFace Inc. team and Microsoft Corporation.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Training and inference using the library models for sequence classification on GLUE (Bert, Albert) with PABEE."""
+
+import argparse
+import glob
+import json
+import logging
+import os
+import random
+
+import numpy as np
+import torch
+from pabee.modeling_pabee_albert import AlbertForSequenceClassificationWithPabee
+from pabee.modeling_pabee_bert import BertForSequenceClassificationWithPabee
+from torch import nn
+from torch.utils.data import DataLoader, RandomSampler, SequentialSampler, TensorDataset
+from torch.utils.data.distributed import DistributedSampler
+from tqdm import tqdm, trange
+
+import transformers
+from transformers import (
+ WEIGHTS_NAME,
+ AdamW,
+ AlbertConfig,
+ AlbertTokenizer,
+ BertConfig,
+ BertTokenizer,
+ get_linear_schedule_with_warmup,
+)
+from transformers import glue_compute_metrics as compute_metrics
+from transformers import glue_convert_examples_to_features as convert_examples_to_features
+from transformers import glue_output_modes as output_modes
+from transformers import glue_processors as processors
+from transformers.trainer_utils import is_main_process
+
+
+try:
+ from torch.utils.tensorboard import SummaryWriter
+except ImportError:
+ from tensorboardX import SummaryWriter
+
+
+logger = logging.getLogger(__name__)
+
+MODEL_CLASSES = {
+ "bert": (BertConfig, BertForSequenceClassificationWithPabee, BertTokenizer),
+ "albert": (AlbertConfig, AlbertForSequenceClassificationWithPabee, AlbertTokenizer),
+}
+
+
+def set_seed(args):
+ random.seed(args.seed)
+ np.random.seed(args.seed)
+ torch.manual_seed(args.seed)
+ if args.n_gpu > 0:
+ torch.cuda.manual_seed_all(args.seed)
+
+
+def train(args, train_dataset, model, tokenizer):
+ """Train the model"""
+ if args.local_rank in [-1, 0]:
+ tb_writer = SummaryWriter()
+
+ args.train_batch_size = args.per_gpu_train_batch_size * max(1, args.n_gpu)
+ train_sampler = RandomSampler(train_dataset) if args.local_rank == -1 else DistributedSampler(train_dataset)
+ train_dataloader = DataLoader(train_dataset, sampler=train_sampler, batch_size=args.train_batch_size)
+
+ if args.max_steps > 0:
+ t_total = args.max_steps
+ args.num_train_epochs = args.max_steps // (len(train_dataloader) // args.gradient_accumulation_steps) + 1
+ else:
+ t_total = len(train_dataloader) // args.gradient_accumulation_steps * args.num_train_epochs
+
+ # Prepare optimizer and schedule (linear warmup and decay)
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {"params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)], "weight_decay": 0.0},
+ ]
+
+ optimizer = AdamW(optimizer_grouped_parameters, lr=args.learning_rate, eps=args.adam_epsilon)
+ scheduler = get_linear_schedule_with_warmup(
+ optimizer, num_warmup_steps=args.warmup_steps, num_training_steps=t_total
+ )
+
+ # Check if saved optimizer or scheduler states exist
+ if os.path.isfile(os.path.join(args.model_name_or_path, "optimizer.pt")) and os.path.isfile(
+ os.path.join(args.model_name_or_path, "scheduler.pt")
+ ):
+ # Load in optimizer and scheduler states
+ optimizer.load_state_dict(torch.load(os.path.join(args.model_name_or_path, "optimizer.pt")))
+ scheduler.load_state_dict(torch.load(os.path.join(args.model_name_or_path, "scheduler.pt")))
+
+ if args.fp16:
+ try:
+ from apex import amp
+ except ImportError:
+ raise ImportError("Please install apex from https://www.github.com/nvidia/apex to use fp16 training.")
+ model, optimizer = amp.initialize(model, optimizer, opt_level=args.fp16_opt_level)
+
+ # multi-gpu training (should be after apex fp16 initialization)
+ if args.n_gpu > 1:
+ model = nn.DataParallel(model)
+
+ # Distributed training (should be after apex fp16 initialization)
+ if args.local_rank != -1:
+ model = nn.parallel.DistributedDataParallel(
+ model,
+ device_ids=[args.local_rank],
+ output_device=args.local_rank,
+ find_unused_parameters=True,
+ )
+
+ # Train!
+ logger.info("***** Running training *****")
+ logger.info(" Num examples = %d", len(train_dataset))
+ logger.info(" Num Epochs = %d", args.num_train_epochs)
+ logger.info(" Instantaneous batch size per GPU = %d", args.per_gpu_train_batch_size)
+ logger.info(
+ " Total train batch size (w. parallel, distributed & accumulation) = %d",
+ args.train_batch_size
+ * args.gradient_accumulation_steps
+ * (torch.distributed.get_world_size() if args.local_rank != -1 else 1),
+ )
+ logger.info(" Gradient Accumulation steps = %d", args.gradient_accumulation_steps)
+ logger.info(" Total optimization steps = %d", t_total)
+
+ global_step = 0
+ epochs_trained = 0
+ steps_trained_in_current_epoch = 0
+ # Check if continuing training from a checkpoint
+ if os.path.exists(args.model_name_or_path):
+ # set global_step to global_step of last saved checkpoint from model path
+ global_step = int(args.model_name_or_path.split("-")[-1].split("/")[0])
+ epochs_trained = global_step // (len(train_dataloader) // args.gradient_accumulation_steps)
+ steps_trained_in_current_epoch = global_step % (len(train_dataloader) // args.gradient_accumulation_steps)
+
+ logger.info(" Continuing training from checkpoint, will skip to saved global_step")
+ logger.info(" Continuing training from epoch %d", epochs_trained)
+ logger.info(" Continuing training from global step %d", global_step)
+ logger.info(
+ " Will skip the first %d steps in the first epoch",
+ steps_trained_in_current_epoch,
+ )
+
+ tr_loss, logging_loss = 0.0, 0.0
+ model.zero_grad()
+ train_iterator = trange(
+ epochs_trained,
+ int(args.num_train_epochs),
+ desc="Epoch",
+ disable=args.local_rank not in [-1, 0],
+ )
+ set_seed(args) # Added here for reproducibility
+ for _ in train_iterator:
+ epoch_iterator = tqdm(train_dataloader, desc="Iteration", disable=args.local_rank not in [-1, 0])
+ for step, batch in enumerate(epoch_iterator):
+ # Skip past any already trained steps if resuming training
+ if steps_trained_in_current_epoch > 0:
+ steps_trained_in_current_epoch -= 1
+ continue
+
+ model.train()
+ batch = tuple(t.to(args.device) for t in batch)
+ inputs = {
+ "input_ids": batch[0],
+ "attention_mask": batch[1],
+ "labels": batch[3],
+ }
+ inputs["token_type_ids"] = batch[2]
+ outputs = model(**inputs)
+ loss = outputs[0] # model outputs are always tuple in transformers (see doc)
+
+ if args.n_gpu > 1:
+ loss = loss.mean() # mean() to average on multi-gpu parallel training
+ if args.gradient_accumulation_steps > 1:
+ loss = loss / args.gradient_accumulation_steps
+
+ if args.fp16:
+ with amp.scale_loss(loss, optimizer) as scaled_loss:
+ scaled_loss.backward()
+ else:
+ loss.backward()
+
+ tr_loss += loss.item()
+ if (step + 1) % args.gradient_accumulation_steps == 0:
+ if args.fp16:
+ nn.utils.clip_grad_norm_(amp.master_params(optimizer), args.max_grad_norm)
+ else:
+ nn.utils.clip_grad_norm_(model.parameters(), args.max_grad_norm)
+
+ optimizer.step()
+ scheduler.step() # Update learning rate schedule
+ model.zero_grad()
+ global_step += 1
+
+ if args.local_rank in [-1, 0] and args.logging_steps > 0 and global_step % args.logging_steps == 0:
+ logs = {}
+ if (
+ args.local_rank == -1 and args.evaluate_during_training
+ ): # Only evaluate when single GPU otherwise metrics may not average well
+ results = evaluate(args, model, tokenizer)
+ for key, value in results.items():
+ eval_key = "eval_{}".format(key)
+ logs[eval_key] = value
+
+ loss_scalar = (tr_loss - logging_loss) / args.logging_steps
+ learning_rate_scalar = scheduler.get_lr()[0]
+ logs["learning_rate"] = learning_rate_scalar
+ logs["loss"] = loss_scalar
+ logging_loss = tr_loss
+
+ for key, value in logs.items():
+ tb_writer.add_scalar(key, value, global_step)
+ print(json.dumps({**logs, **{"step": global_step}}))
+
+ if args.local_rank in [-1, 0] and args.save_steps > 0 and global_step % args.save_steps == 0:
+ # Save model checkpoint
+ output_dir = os.path.join(args.output_dir, "checkpoint-{}".format(global_step))
+ model_to_save = (
+ model.module if hasattr(model, "module") else model
+ ) # Take care of distributed/parallel training
+ model_to_save.save_pretrained(output_dir)
+ tokenizer.save_pretrained(output_dir)
+
+ torch.save(args, os.path.join(output_dir, "training_args.bin"))
+ logger.info("Saving model checkpoint to %s", output_dir)
+
+ torch.save(optimizer.state_dict(), os.path.join(output_dir, "optimizer.pt"))
+ torch.save(scheduler.state_dict(), os.path.join(output_dir, "scheduler.pt"))
+ logger.info("Saving optimizer and scheduler states to %s", output_dir)
+
+ if args.max_steps > 0 and global_step > args.max_steps:
+ epoch_iterator.close()
+ break
+ if args.max_steps > 0 and global_step > args.max_steps:
+ train_iterator.close()
+ break
+
+ if args.local_rank in [-1, 0]:
+ tb_writer.close()
+
+ return global_step, tr_loss / global_step
+
+
+def evaluate(args, model, tokenizer, prefix="", patience=0):
+ if args.model_type == "albert":
+ model.albert.set_regression_threshold(args.regression_threshold)
+ model.albert.set_patience(patience)
+ model.albert.reset_stats()
+ elif args.model_type == "bert":
+ model.bert.set_regression_threshold(args.regression_threshold)
+ model.bert.set_patience(patience)
+ model.bert.reset_stats()
+ else:
+ raise NotImplementedError()
+
+ # Loop to handle MNLI double evaluation (matched, mis-matched)
+ eval_task_names = ("mnli", "mnli-mm") if args.task_name == "mnli" else (args.task_name,)
+ eval_outputs_dirs = (args.output_dir, args.output_dir + "-MM") if args.task_name == "mnli" else (args.output_dir,)
+
+ results = {}
+ for eval_task, eval_output_dir in zip(eval_task_names, eval_outputs_dirs):
+ eval_dataset = load_and_cache_examples(args, eval_task, tokenizer, evaluate=True)
+
+ if not os.path.exists(eval_output_dir) and args.local_rank in [-1, 0]:
+ os.makedirs(eval_output_dir)
+
+ args.eval_batch_size = args.per_gpu_eval_batch_size * max(1, args.n_gpu)
+ # Note that DistributedSampler samples randomly
+ eval_sampler = SequentialSampler(eval_dataset)
+ eval_dataloader = DataLoader(eval_dataset, sampler=eval_sampler, batch_size=args.eval_batch_size)
+
+ # multi-gpu eval
+ if args.n_gpu > 1 and not isinstance(model, nn.DataParallel):
+ model = nn.DataParallel(model)
+
+ # Eval!
+ logger.info("***** Running evaluation {} *****".format(prefix))
+ logger.info(" Num examples = %d", len(eval_dataset))
+ logger.info(" Batch size = %d", args.eval_batch_size)
+ eval_loss = 0.0
+ nb_eval_steps = 0
+ preds = None
+ out_label_ids = None
+ for batch in tqdm(eval_dataloader, desc="Evaluating"):
+ model.eval()
+ batch = tuple(t.to(args.device) for t in batch)
+
+ with torch.no_grad():
+ inputs = {
+ "input_ids": batch[0],
+ "attention_mask": batch[1],
+ "labels": batch[3],
+ }
+ inputs["token_type_ids"] = batch[2]
+ outputs = model(**inputs)
+ tmp_eval_loss, logits = outputs[:2]
+
+ eval_loss += tmp_eval_loss.mean().item()
+ nb_eval_steps += 1
+ if preds is None:
+ preds = logits.detach().cpu().numpy()
+ out_label_ids = inputs["labels"].detach().cpu().numpy()
+ else:
+ preds = np.append(preds, logits.detach().cpu().numpy(), axis=0)
+ out_label_ids = np.append(out_label_ids, inputs["labels"].detach().cpu().numpy(), axis=0)
+
+ eval_loss = eval_loss / nb_eval_steps
+ if args.output_mode == "classification":
+ preds = np.argmax(preds, axis=1)
+ elif args.output_mode == "regression":
+ preds = np.squeeze(preds)
+ result = compute_metrics(eval_task, preds, out_label_ids)
+ results.update(result)
+
+ output_eval_file = os.path.join(eval_output_dir, prefix, "eval_results.txt")
+ with open(output_eval_file, "w") as writer:
+ logger.info("***** Eval results {} *****".format(prefix))
+ for key in sorted(result.keys()):
+ logger.info(" %s = %s", key, str(result[key]))
+ print(" %s = %s" % (key, str(result[key])))
+ writer.write("%s = %s\n" % (key, str(result[key])))
+
+ if args.eval_all_checkpoints and patience != 0:
+ if args.model_type == "albert":
+ model.albert.log_stats()
+ elif args.model_type == "bert":
+ model.bert.log_stats()
+ else:
+ raise NotImplementedError()
+
+ return results
+
+
+def load_and_cache_examples(args, task, tokenizer, evaluate=False):
+ if args.local_rank not in [-1, 0] and not evaluate:
+ torch.distributed.barrier() # Make sure only the first process in distributed training process the dataset, and the others will use the cache
+
+ processor = processors[task]()
+ output_mode = output_modes[task]
+ # Load data features from cache or dataset file
+ cached_features_file = os.path.join(
+ args.data_dir,
+ "cached_{}_{}_{}_{}".format(
+ "dev" if evaluate else "train",
+ list(filter(None, args.model_name_or_path.split("/"))).pop(),
+ str(args.max_seq_length),
+ str(task),
+ ),
+ )
+ if os.path.exists(cached_features_file) and not args.overwrite_cache:
+ logger.info("Loading features from cached file %s", cached_features_file)
+ features = torch.load(cached_features_file)
+ else:
+ logger.info("Creating features from dataset file at %s", args.data_dir)
+ label_list = processor.get_labels()
+ if task in ["mnli", "mnli-mm"] and args.model_type in ["roberta", "xlmroberta"]:
+ # HACK(label indices are swapped in RoBERTa pretrained model)
+ label_list[1], label_list[2] = label_list[2], label_list[1]
+ examples = (
+ processor.get_dev_examples(args.data_dir) if evaluate else processor.get_train_examples(args.data_dir)
+ )
+ features = convert_examples_to_features(
+ examples,
+ tokenizer,
+ label_list=label_list,
+ max_length=args.max_seq_length,
+ output_mode=output_mode,
+ )
+ if args.local_rank in [-1, 0]:
+ logger.info("Saving features into cached file %s", cached_features_file)
+ torch.save(features, cached_features_file)
+
+ if args.local_rank == 0 and not evaluate:
+ torch.distributed.barrier() # Make sure only the first process in distributed training process the dataset, and the others will use the cache
+
+ # Convert to Tensors and build dataset
+ all_input_ids = torch.tensor([f.input_ids for f in features], dtype=torch.long)
+ all_attention_mask = torch.tensor([f.attention_mask for f in features], dtype=torch.long)
+ all_token_type_ids = torch.tensor([f.token_type_ids for f in features], dtype=torch.long)
+ if output_mode == "classification":
+ all_labels = torch.tensor([f.label for f in features], dtype=torch.long)
+ elif output_mode == "regression":
+ all_labels = torch.tensor([f.label for f in features], dtype=torch.float)
+
+ dataset = TensorDataset(all_input_ids, all_attention_mask, all_token_type_ids, all_labels)
+ return dataset
+
+
+def main():
+ parser = argparse.ArgumentParser()
+
+ # Required parameters
+ parser.add_argument(
+ "--data_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The input data dir. Should contain the .tsv files (or other data files) for the task.",
+ )
+ parser.add_argument(
+ "--model_type",
+ default=None,
+ type=str,
+ required=True,
+ help="Model type selected in the list: " + ", ".join(MODEL_CLASSES.keys()),
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ default=None,
+ type=str,
+ required=True,
+ help="Path to pre-trained model or shortcut name.",
+ )
+ parser.add_argument(
+ "--task_name",
+ default=None,
+ type=str,
+ required=True,
+ help="The name of the task to train selected in the list: " + ", ".join(processors.keys()),
+ )
+ parser.add_argument(
+ "--output_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The output directory where the model predictions and checkpoints will be written.",
+ )
+ parser.add_argument(
+ "--patience",
+ default="0",
+ type=str,
+ required=False,
+ )
+ parser.add_argument(
+ "--regression_threshold",
+ default=0,
+ type=float,
+ required=False,
+ )
+
+ # Other parameters
+ parser.add_argument(
+ "--config_name",
+ default="",
+ type=str,
+ help="Pretrained config name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ default="",
+ type=str,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--cache_dir",
+ default="",
+ type=str,
+ help="Where do you want to store the pre-trained models downloaded from huggingface.co",
+ )
+ parser.add_argument(
+ "--max_seq_length",
+ default=128,
+ type=int,
+ help=(
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ ),
+ )
+ parser.add_argument("--do_train", action="store_true", help="Whether to run training.")
+ parser.add_argument("--do_eval", action="store_true", help="Whether to run eval on the dev set.")
+ parser.add_argument(
+ "--evaluate_during_training",
+ action="store_true",
+ help="Run evaluation during training at each logging step.",
+ )
+ parser.add_argument(
+ "--do_lower_case",
+ action="store_true",
+ help="Set this flag if you are using an uncased model.",
+ )
+
+ parser.add_argument(
+ "--per_gpu_train_batch_size",
+ default=8,
+ type=int,
+ help="Batch size per GPU/CPU for training.",
+ )
+ parser.add_argument(
+ "--per_gpu_eval_batch_size",
+ default=1,
+ type=int,
+ help="Batch size per GPU/CPU for evaluation.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ default=5e-5,
+ type=float,
+ help="The initial learning rate for Adam.",
+ )
+ parser.add_argument("--weight_decay", default=0.0, type=float, help="Weight decay if we apply some.")
+ parser.add_argument("--adam_epsilon", default=1e-8, type=float, help="Epsilon for Adam optimizer.")
+ parser.add_argument("--max_grad_norm", default=1.0, type=float, help="Max gradient norm.")
+ parser.add_argument(
+ "--num_train_epochs",
+ default=3.0,
+ type=float,
+ help="Total number of training epochs to perform.",
+ )
+ parser.add_argument(
+ "--max_steps",
+ default=-1,
+ type=int,
+ help="If > 0: set total number of training steps to perform. Override num_train_epochs.",
+ )
+ parser.add_argument("--warmup_steps", default=0, type=int, help="Linear warmup over warmup_steps.")
+
+ parser.add_argument("--logging_steps", type=int, default=500, help="Log every X updates steps.")
+ parser.add_argument(
+ "--save_steps",
+ type=int,
+ default=500,
+ help="Save checkpoint every X updates steps.",
+ )
+ parser.add_argument(
+ "--eval_all_checkpoints",
+ action="store_true",
+ help="Evaluate all checkpoints starting with the same prefix as model_name ending and ending with step number",
+ )
+ parser.add_argument("--no_cuda", action="store_true", help="Avoid using CUDA when available")
+ parser.add_argument(
+ "--overwrite_output_dir",
+ action="store_true",
+ help="Overwrite the content of the output directory",
+ )
+ parser.add_argument(
+ "--overwrite_cache",
+ action="store_true",
+ help="Overwrite the cached training and evaluation sets",
+ )
+ parser.add_argument("--seed", type=int, default=42, help="random seed for initialization")
+
+ parser.add_argument(
+ "--fp16",
+ action="store_true",
+ help="Whether to use 16-bit (mixed) precision (through NVIDIA apex) instead of 32-bit",
+ )
+ parser.add_argument(
+ "--fp16_opt_level",
+ type=str,
+ default="O1",
+ help=(
+ "For fp16: Apex AMP optimization level selected in ['O0', 'O1', 'O2', and 'O3']. "
+ "See details at https://nvidia.github.io/apex/amp.html"
+ ),
+ )
+ parser.add_argument(
+ "--local_rank",
+ type=int,
+ default=-1,
+ help="For distributed training: local_rank",
+ )
+ parser.add_argument("--server_ip", type=str, default="", help="For distant debugging.")
+ parser.add_argument("--server_port", type=str, default="", help="For distant debugging.")
+ args = parser.parse_args()
+
+ if (
+ os.path.exists(args.output_dir)
+ and os.listdir(args.output_dir)
+ and args.do_train
+ and not args.overwrite_output_dir
+ ):
+ raise ValueError(
+ "Output directory ({}) already exists and is not empty. Use --overwrite_output_dir to overcome.".format(
+ args.output_dir
+ )
+ )
+
+ # Setup distant debugging if needed
+ if args.server_ip and args.server_port:
+ # Distant debugging - see https://code.visualstudio.com/docs/python/debugging#_attach-to-a-local-script
+ import ptvsd
+
+ print("Waiting for debugger attach")
+ ptvsd.enable_attach(address=(args.server_ip, args.server_port), redirect_output=True)
+ ptvsd.wait_for_attach()
+
+ # Setup CUDA, GPU & distributed training
+ if args.local_rank == -1 or args.no_cuda:
+ device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
+ args.n_gpu = torch.cuda.device_count()
+ else: # Initializes the distributed backend which will take care of synchronizing nodes/GPUs
+ torch.cuda.set_device(args.local_rank)
+ device = torch.device("cuda", args.local_rank)
+ torch.distributed.init_process_group(backend="nccl")
+ args.n_gpu = 1
+ args.device = device
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO if args.local_rank in [-1, 0] else logging.WARN,
+ )
+ logger.warning(
+ "Process rank: %s, device: %s, n_gpu: %s, distributed training: %s, 16-bits training: %s",
+ args.local_rank,
+ device,
+ args.n_gpu,
+ bool(args.local_rank != -1),
+ args.fp16,
+ )
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ if is_main_process(args.local_rank):
+ transformers.utils.logging.set_verbosity_info()
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+ # Set seed
+ set_seed(args)
+
+ # Prepare GLUE task
+ args.task_name = args.task_name.lower()
+ if args.task_name not in processors:
+ raise ValueError("Task not found: %s" % (args.task_name))
+ processor = processors[args.task_name]()
+ args.output_mode = output_modes[args.task_name]
+ label_list = processor.get_labels()
+ num_labels = len(label_list)
+
+ if args.patience != "0" and args.per_gpu_eval_batch_size != 1:
+ raise ValueError("The eval batch size must be 1 with PABEE inference on.")
+
+ # Load pretrained model and tokenizer
+ if args.local_rank not in [-1, 0]:
+ torch.distributed.barrier() # Make sure only the first process in distributed training will download model & vocab
+
+ args.model_type = args.model_type.lower()
+ config_class, model_class, tokenizer_class = MODEL_CLASSES[args.model_type]
+ config = config_class.from_pretrained(
+ args.config_name if args.config_name else args.model_name_or_path,
+ num_labels=num_labels,
+ finetuning_task=args.task_name,
+ cache_dir=args.cache_dir if args.cache_dir else None,
+ )
+ tokenizer = tokenizer_class.from_pretrained(
+ args.tokenizer_name if args.tokenizer_name else args.model_name_or_path,
+ do_lower_case=args.do_lower_case,
+ cache_dir=args.cache_dir if args.cache_dir else None,
+ )
+ model = model_class.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ cache_dir=args.cache_dir if args.cache_dir else None,
+ )
+
+ if args.local_rank == 0:
+ torch.distributed.barrier() # Make sure only the first process in distributed training will download model & vocab
+
+ model.to(args.device)
+
+ print("Total Model Parameters:", sum(param.numel() for param in model.parameters()))
+ output_layers_param_num = sum(param.numel() for param in model.classifiers.parameters())
+ print("Output Layers Parameters:", output_layers_param_num)
+ single_output_layer_param_num = sum(param.numel() for param in model.classifiers[0].parameters())
+ print(
+ "Added Output Layers Parameters:",
+ output_layers_param_num - single_output_layer_param_num,
+ )
+
+ logger.info("Training/evaluation parameters %s", args)
+
+ # Training
+ if args.do_train:
+ train_dataset = load_and_cache_examples(args, args.task_name, tokenizer, evaluate=False)
+ global_step, tr_loss = train(args, train_dataset, model, tokenizer)
+ logger.info(" global_step = %s, average loss = %s", global_step, tr_loss)
+
+ # Saving best-practices: if you use defaults names for the model, you can reload it using from_pretrained()
+ if args.do_train and (args.local_rank == -1 or torch.distributed.get_rank() == 0):
+ logger.info("Saving model checkpoint to %s", args.output_dir)
+ # Save a trained model, configuration and tokenizer using `save_pretrained()`.
+ # They can then be reloaded using `from_pretrained()`
+ model_to_save = (
+ model.module if hasattr(model, "module") else model
+ ) # Take care of distributed/parallel training
+ model_to_save.save_pretrained(args.output_dir)
+ tokenizer.save_pretrained(args.output_dir)
+
+ # Good practice: save your training arguments together with the trained model
+ torch.save(args, os.path.join(args.output_dir, "training_args.bin"))
+
+ # Load a trained model and vocabulary that you have fine-tuned
+ model = model_class.from_pretrained(args.output_dir)
+ tokenizer = tokenizer_class.from_pretrained(args.output_dir)
+ model.to(args.device)
+
+ # Evaluation
+ results = {}
+ if args.do_eval and args.local_rank in [-1, 0]:
+ patience_list = [int(x) for x in args.patience.split(",")]
+ tokenizer = tokenizer_class.from_pretrained(args.output_dir, do_lower_case=args.do_lower_case)
+ checkpoints = [args.output_dir]
+ if args.eval_all_checkpoints:
+ checkpoints = [
+ os.path.dirname(c) for c in sorted(glob.glob(args.output_dir + "/**/" + WEIGHTS_NAME, recursive=True))
+ ]
+
+ logger.info("Evaluate the following checkpoints: %s", checkpoints)
+
+ for checkpoint in checkpoints:
+ global_step = checkpoint.split("-")[-1] if len(checkpoints) > 1 else ""
+ prefix = checkpoint.split("/")[-1] if checkpoint.find("checkpoint") != -1 else ""
+
+ model = model_class.from_pretrained(checkpoint)
+ model.to(args.device)
+
+ print(f"Evaluation for checkpoint {prefix}")
+ for patience in patience_list:
+ result = evaluate(args, model, tokenizer, prefix=prefix, patience=patience)
+ result = {k + "_{}".format(global_step): v for k, v in result.items()}
+ results.update(result)
+ return results
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/test_run_glue_with_pabee.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/test_run_glue_with_pabee.py
new file mode 100644
index 0000000000000000000000000000000000000000..5516924f0f2fb7408d88470cc890132ce231f095
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bert-loses-patience/test_run_glue_with_pabee.py
@@ -0,0 +1,51 @@
+import argparse
+import logging
+import sys
+from unittest.mock import patch
+
+import run_glue_with_pabee
+
+from transformers.testing_utils import TestCasePlus
+
+
+logging.basicConfig(level=logging.DEBUG)
+
+logger = logging.getLogger()
+
+
+def get_setup_file():
+ parser = argparse.ArgumentParser()
+ parser.add_argument("-f")
+ args = parser.parse_args()
+ return args.f
+
+
+class PabeeTests(TestCasePlus):
+ def test_run_glue(self):
+ stream_handler = logging.StreamHandler(sys.stdout)
+ logger.addHandler(stream_handler)
+
+ tmp_dir = self.get_auto_remove_tmp_dir()
+ testargs = f"""
+ run_glue_with_pabee.py
+ --model_type albert
+ --model_name_or_path albert/albert-base-v2
+ --data_dir ./tests/fixtures/tests_samples/MRPC/
+ --output_dir {tmp_dir}
+ --overwrite_output_dir
+ --task_name mrpc
+ --do_train
+ --do_eval
+ --per_gpu_train_batch_size=2
+ --per_gpu_eval_batch_size=1
+ --learning_rate=2e-5
+ --max_steps=50
+ --warmup_steps=2
+ --seed=42
+ --max_seq_length=128
+ """.split()
+
+ with patch.object(sys, "argv", testargs):
+ result = run_glue_with_pabee.main()
+ for value in result.values():
+ self.assertGreaterEqual(value, 0.75)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..7109c0fb72be1bf438efb767d918770fffffc350
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/README.md
@@ -0,0 +1,61 @@
+# Text Summarization with Pretrained Encoders
+
+This folder contains part of the code necessary to reproduce the results on abstractive summarization from the article [Text Summarization with Pretrained Encoders](https://arxiv.org/pdf/1908.08345.pdf) by [Yang Liu](https://nlp-yang.github.io/) and [Mirella Lapata](https://homepages.inf.ed.ac.uk/mlap/). It can also be used to summarize any document.
+
+The original code can be found on the Yang Liu's [github repository](https://github.com/nlpyang/PreSumm).
+
+The model is loaded with the pre-trained weights for the abstractive summarization model trained on the CNN/Daily Mail dataset with an extractive and then abstractive tasks.
+
+## Setup
+
+```bash
+git clone https://github.com/huggingface/transformers && cd transformers
+pip install .
+pip install nltk py-rouge
+cd examples/seq2seq/bertabs
+```
+
+## Reproduce the authors' ROUGE score
+
+To be able to reproduce the authors' results on the CNN/Daily Mail dataset you first need to download both CNN and Daily Mail datasets [from Kyunghyun Cho's website](https://cs.nyu.edu/~kcho/DMQA/) (the links next to "Stories") in the same folder. Then uncompress the archives by running:
+
+```bash
+tar -xvf cnn_stories.tgz && tar -xvf dailymail_stories.tgz
+```
+
+And move all the stories to the same folder. We will refer as `$DATA_PATH` the path to where you uncompressed both archive. Then run the following in the same folder as `run_summarization.py`:
+
+```bash
+python run_summarization.py \
+ --documents_dir $DATA_PATH \
+ --summaries_output_dir $SUMMARIES_PATH \ # optional
+ --no_cuda false \
+ --batch_size 4 \
+ --min_length 50 \
+ --max_length 200 \
+ --beam_size 5 \
+ --alpha 0.95 \
+ --block_trigram true \
+ --compute_rouge true
+```
+
+The scripts executes on GPU if one is available and if `no_cuda` is not set to `true`. Inference on multiple GPUs is not supported yet. The ROUGE scores will be displayed in the console at the end of evaluation and written in a `rouge_scores.txt` file. The script takes 30 hours to compute with a single Tesla V100 GPU and a batch size of 10 (300,000 texts to summarize).
+
+## Summarize any text
+
+Put the documents that you would like to summarize in a folder (the path to which is referred to as `$DATA_PATH` below) and run the following in the same folder as `run_summarization.py`:
+
+```bash
+python run_summarization.py \
+ --documents_dir $DATA_PATH \
+ --summaries_output_dir $SUMMARIES_PATH \ # optional
+ --no_cuda false \
+ --batch_size 4 \
+ --min_length 50 \
+ --max_length 200 \
+ --beam_size 5 \
+ --alpha 0.95 \
+ --block_trigram true \
+```
+
+You may want to play around with `min_length`, `max_length` and `alpha` to suit your use case. If you want to compute ROUGE on another dataset you will need to tweak the stories/summaries import in `utils_summarization.py` and tell it where to fetch the reference summaries.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/__init__.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/configuration_bertabs.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/configuration_bertabs.py
new file mode 100644
index 0000000000000000000000000000000000000000..4c65cd3395c2f49b4e304d42fa1dd35517179e98
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/configuration_bertabs.py
@@ -0,0 +1,98 @@
+# coding=utf-8
+# Copyright 2019 The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""BertAbs configuration"""
+
+import logging
+
+from transformers import PretrainedConfig
+
+
+logger = logging.getLogger(__name__)
+
+
+BERTABS_FINETUNED_CONFIG_MAP = {
+ "bertabs-finetuned-cnndm": "https://huggingface.co/remi/bertabs-finetuned-cnndm-extractive-abstractive-summarization/resolve/main/config.json",
+}
+
+
+class BertAbsConfig(PretrainedConfig):
+ r"""Class to store the configuration of the BertAbs model.
+
+ Arguments:
+ vocab_size: int
+ Number of tokens in the vocabulary.
+ max_pos: int
+ The maximum sequence length that this model will be used with.
+ enc_layer: int
+ The numner of hidden layers in the Transformer encoder.
+ enc_hidden_size: int
+ The size of the encoder's layers.
+ enc_heads: int
+ The number of attention heads for each attention layer in the encoder.
+ enc_ff_size: int
+ The size of the encoder's feed-forward layers.
+ enc_dropout: int
+ The dropout probability for all fully connected layers in the
+ embeddings, layers, pooler and also the attention probabilities in
+ the encoder.
+ dec_layer: int
+ The numner of hidden layers in the decoder.
+ dec_hidden_size: int
+ The size of the decoder's layers.
+ dec_heads: int
+ The number of attention heads for each attention layer in the decoder.
+ dec_ff_size: int
+ The size of the decoder's feed-forward layers.
+ dec_dropout: int
+ The dropout probability for all fully connected layers in the
+ embeddings, layers, pooler and also the attention probabilities in
+ the decoder.
+ """
+
+ model_type = "bertabs"
+
+ def __init__(
+ self,
+ vocab_size=30522,
+ max_pos=512,
+ enc_layers=6,
+ enc_hidden_size=512,
+ enc_heads=8,
+ enc_ff_size=512,
+ enc_dropout=0.2,
+ dec_layers=6,
+ dec_hidden_size=768,
+ dec_heads=8,
+ dec_ff_size=2048,
+ dec_dropout=0.2,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.vocab_size = vocab_size
+ self.max_pos = max_pos
+
+ self.enc_layers = enc_layers
+ self.enc_hidden_size = enc_hidden_size
+ self.enc_heads = enc_heads
+ self.enc_ff_size = enc_ff_size
+ self.enc_dropout = enc_dropout
+
+ self.dec_layers = dec_layers
+ self.dec_hidden_size = dec_hidden_size
+ self.dec_heads = dec_heads
+ self.dec_ff_size = dec_ff_size
+ self.dec_dropout = dec_dropout
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/convert_bertabs_original_pytorch_checkpoint.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/convert_bertabs_original_pytorch_checkpoint.py
new file mode 100644
index 0000000000000000000000000000000000000000..338ffd21c99353090b24e09a7b47d7932a948e21
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/convert_bertabs_original_pytorch_checkpoint.py
@@ -0,0 +1,185 @@
+# coding=utf-8
+# Copyright 2018 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Convert BertExtAbs's checkpoints.
+
+The script looks like it is doing something trivial but it is not. The "weights"
+proposed by the authors are actually the entire model pickled. We need to load
+the model within the original codebase to be able to only save its `state_dict`.
+"""
+
+import argparse
+import logging
+from collections import namedtuple
+
+import torch
+from model_bertabs import BertAbsSummarizer
+from models.model_builder import AbsSummarizer # The authors' implementation
+
+from transformers import BertTokenizer
+
+
+logging.basicConfig(level=logging.INFO)
+logger = logging.getLogger(__name__)
+
+
+SAMPLE_TEXT = "Hello world! cécé herlolip"
+
+
+BertAbsConfig = namedtuple(
+ "BertAbsConfig",
+ [
+ "temp_dir",
+ "large",
+ "use_bert_emb",
+ "finetune_bert",
+ "encoder",
+ "share_emb",
+ "max_pos",
+ "enc_layers",
+ "enc_hidden_size",
+ "enc_heads",
+ "enc_ff_size",
+ "enc_dropout",
+ "dec_layers",
+ "dec_hidden_size",
+ "dec_heads",
+ "dec_ff_size",
+ "dec_dropout",
+ ],
+)
+
+
+def convert_bertabs_checkpoints(path_to_checkpoints, dump_path):
+ """Copy/paste and tweak the pre-trained weights provided by the creators
+ of BertAbs for the internal architecture.
+ """
+
+ # Instantiate the authors' model with the pre-trained weights
+ config = BertAbsConfig(
+ temp_dir=".",
+ finetune_bert=False,
+ large=False,
+ share_emb=True,
+ use_bert_emb=False,
+ encoder="bert",
+ max_pos=512,
+ enc_layers=6,
+ enc_hidden_size=512,
+ enc_heads=8,
+ enc_ff_size=512,
+ enc_dropout=0.2,
+ dec_layers=6,
+ dec_hidden_size=768,
+ dec_heads=8,
+ dec_ff_size=2048,
+ dec_dropout=0.2,
+ )
+ checkpoints = torch.load(path_to_checkpoints, lambda storage, loc: storage)
+ original = AbsSummarizer(config, torch.device("cpu"), checkpoints)
+ original.eval()
+
+ new_model = BertAbsSummarizer(config, torch.device("cpu"))
+ new_model.eval()
+
+ # -------------------
+ # Convert the weights
+ # -------------------
+
+ logging.info("convert the model")
+ new_model.bert.load_state_dict(original.bert.state_dict())
+ new_model.decoder.load_state_dict(original.decoder.state_dict())
+ new_model.generator.load_state_dict(original.generator.state_dict())
+
+ # ----------------------------------
+ # Make sure the outpus are identical
+ # ----------------------------------
+
+ logging.info("Make sure that the models' outputs are identical")
+ tokenizer = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+
+ # prepare the model inputs
+ encoder_input_ids = tokenizer.encode("This is sample éàalj'-.")
+ encoder_input_ids.extend([tokenizer.pad_token_id] * (512 - len(encoder_input_ids)))
+ encoder_input_ids = torch.tensor(encoder_input_ids).unsqueeze(0)
+ decoder_input_ids = tokenizer.encode("This is sample 3 éàalj'-.")
+ decoder_input_ids.extend([tokenizer.pad_token_id] * (512 - len(decoder_input_ids)))
+ decoder_input_ids = torch.tensor(decoder_input_ids).unsqueeze(0)
+
+ # failsafe to make sure the weights reset does not affect the
+ # loaded weights.
+ assert torch.max(torch.abs(original.generator[0].weight - new_model.generator[0].weight)) == 0
+
+ # forward pass
+ src = encoder_input_ids
+ tgt = decoder_input_ids
+ segs = token_type_ids = None
+ clss = None
+ mask_src = encoder_attention_mask = None
+ mask_tgt = decoder_attention_mask = None
+ mask_cls = None
+
+ # The original model does not apply the geneator layer immediatly but rather in
+ # the beam search (where it combines softmax + linear layer). Since we already
+ # apply the softmax in our generation process we only apply the linear layer here.
+ # We make sure that the outputs of the full stack are identical
+ output_original_model = original(src, tgt, segs, clss, mask_src, mask_tgt, mask_cls)[0]
+ output_original_generator = original.generator(output_original_model)
+
+ output_converted_model = new_model(
+ encoder_input_ids, decoder_input_ids, token_type_ids, encoder_attention_mask, decoder_attention_mask
+ )[0]
+ output_converted_generator = new_model.generator(output_converted_model)
+
+ maximum_absolute_difference = torch.max(torch.abs(output_converted_model - output_original_model)).item()
+ print("Maximum absolute difference beween weights: {:.2f}".format(maximum_absolute_difference))
+ maximum_absolute_difference = torch.max(torch.abs(output_converted_generator - output_original_generator)).item()
+ print("Maximum absolute difference beween weights: {:.2f}".format(maximum_absolute_difference))
+
+ are_identical = torch.allclose(output_converted_model, output_original_model, atol=1e-3)
+ if are_identical:
+ logging.info("all weights are equal up to 1e-3")
+ else:
+ raise ValueError("the weights are different. The new model is likely different from the original one.")
+
+ # The model has been saved with torch.save(model) and this is bound to the exact
+ # directory structure. We save the state_dict instead.
+ logging.info("saving the model's state dictionary")
+ torch.save(
+ new_model.state_dict(), "./bertabs-finetuned-cnndm-extractive-abstractive-summarization/pytorch_model.bin"
+ )
+
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser()
+ parser.add_argument(
+ "--bertabs_checkpoint_path",
+ default=None,
+ type=str,
+ required=True,
+ help="Path the official PyTorch dump.",
+ )
+ parser.add_argument(
+ "--pytorch_dump_folder_path",
+ default=None,
+ type=str,
+ required=True,
+ help="Path to the output PyTorch model.",
+ )
+ args = parser.parse_args()
+
+ convert_bertabs_checkpoints(
+ args.bertabs_checkpoint_path,
+ args.pytorch_dump_folder_path,
+ )
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/modeling_bertabs.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/modeling_bertabs.py
new file mode 100644
index 0000000000000000000000000000000000000000..c2c6a54be75ffa9f334d29617b6cda140aa5b486
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/modeling_bertabs.py
@@ -0,0 +1,1054 @@
+# MIT License
+
+# Copyright (c) 2019 Yang Liu and the HuggingFace team
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+import copy
+import math
+
+import numpy as np
+import torch
+from configuration_bertabs import BertAbsConfig
+from torch import nn
+from torch.nn.init import xavier_uniform_
+
+from transformers import BertConfig, BertModel, PreTrainedModel
+
+
+MAX_SIZE = 5000
+
+
+class BertAbsPreTrainedModel(PreTrainedModel):
+ config_class = BertAbsConfig
+ load_tf_weights = False
+ base_model_prefix = "bert"
+
+
+class BertAbs(BertAbsPreTrainedModel):
+ def __init__(self, args, checkpoint=None, bert_extractive_checkpoint=None):
+ super().__init__(args)
+ self.args = args
+ self.bert = Bert()
+
+ # If pre-trained weights are passed for Bert, load these.
+ load_bert_pretrained_extractive = True if bert_extractive_checkpoint else False
+ if load_bert_pretrained_extractive:
+ self.bert.model.load_state_dict(
+ {n[11:]: p for n, p in bert_extractive_checkpoint.items() if n.startswith("bert.model")},
+ strict=True,
+ )
+
+ self.vocab_size = self.bert.model.config.vocab_size
+
+ if args.max_pos > 512:
+ my_pos_embeddings = nn.Embedding(args.max_pos, self.bert.model.config.hidden_size)
+ my_pos_embeddings.weight.data[:512] = self.bert.model.embeddings.position_embeddings.weight.data
+ my_pos_embeddings.weight.data[512:] = self.bert.model.embeddings.position_embeddings.weight.data[-1][
+ None, :
+ ].repeat(args.max_pos - 512, 1)
+ self.bert.model.embeddings.position_embeddings = my_pos_embeddings
+ tgt_embeddings = nn.Embedding(self.vocab_size, self.bert.model.config.hidden_size, padding_idx=0)
+
+ tgt_embeddings.weight = copy.deepcopy(self.bert.model.embeddings.word_embeddings.weight)
+
+ self.decoder = TransformerDecoder(
+ self.args.dec_layers,
+ self.args.dec_hidden_size,
+ heads=self.args.dec_heads,
+ d_ff=self.args.dec_ff_size,
+ dropout=self.args.dec_dropout,
+ embeddings=tgt_embeddings,
+ vocab_size=self.vocab_size,
+ )
+
+ gen_func = nn.LogSoftmax(dim=-1)
+ self.generator = nn.Sequential(nn.Linear(args.dec_hidden_size, args.vocab_size), gen_func)
+ self.generator[0].weight = self.decoder.embeddings.weight
+
+ load_from_checkpoints = False if checkpoint is None else True
+ if load_from_checkpoints:
+ self.load_state_dict(checkpoint)
+
+ def init_weights(self):
+ for module in self.decoder.modules():
+ if isinstance(module, (nn.Linear, nn.Embedding)):
+ module.weight.data.normal_(mean=0.0, std=0.02)
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ if isinstance(module, nn.Linear) and module.bias is not None:
+ module.bias.data.zero_()
+ for p in self.generator.parameters():
+ if p.dim() > 1:
+ xavier_uniform_(p)
+ else:
+ p.data.zero_()
+
+ def forward(
+ self,
+ encoder_input_ids,
+ decoder_input_ids,
+ token_type_ids,
+ encoder_attention_mask,
+ decoder_attention_mask,
+ ):
+ encoder_output = self.bert(
+ input_ids=encoder_input_ids,
+ token_type_ids=token_type_ids,
+ attention_mask=encoder_attention_mask,
+ )
+ encoder_hidden_states = encoder_output[0]
+ dec_state = self.decoder.init_decoder_state(encoder_input_ids, encoder_hidden_states)
+ decoder_outputs, _ = self.decoder(decoder_input_ids[:, :-1], encoder_hidden_states, dec_state)
+ return decoder_outputs
+
+
+class Bert(nn.Module):
+ """This class is not really necessary and should probably disappear."""
+
+ def __init__(self):
+ super().__init__()
+ config = BertConfig.from_pretrained("google-bert/bert-base-uncased")
+ self.model = BertModel(config)
+
+ def forward(self, input_ids, attention_mask=None, token_type_ids=None, **kwargs):
+ self.eval()
+ with torch.no_grad():
+ encoder_outputs, _ = self.model(
+ input_ids, token_type_ids=token_type_ids, attention_mask=attention_mask, **kwargs
+ )
+ return encoder_outputs
+
+
+class TransformerDecoder(nn.Module):
+ """
+ The Transformer decoder from "Attention is All You Need".
+
+ Args:
+ num_layers (int): number of encoder layers.
+ d_model (int): size of the model
+ heads (int): number of heads
+ d_ff (int): size of the inner FF layer
+ dropout (float): dropout parameters
+ embeddings (:obj:`onmt.modules.Embeddings`):
+ embeddings to use, should have positional encodings
+ attn_type (str): if using a separate copy attention
+ """
+
+ def __init__(self, num_layers, d_model, heads, d_ff, dropout, embeddings, vocab_size):
+ super().__init__()
+
+ # Basic attributes.
+ self.decoder_type = "transformer"
+ self.num_layers = num_layers
+ self.embeddings = embeddings
+ self.pos_emb = PositionalEncoding(dropout, self.embeddings.embedding_dim)
+
+ # Build TransformerDecoder.
+ self.transformer_layers = nn.ModuleList(
+ [TransformerDecoderLayer(d_model, heads, d_ff, dropout) for _ in range(num_layers)]
+ )
+
+ self.layer_norm = nn.LayerNorm(d_model, eps=1e-6)
+
+ # forward(input_ids, attention_mask, encoder_hidden_states, encoder_attention_mask)
+ # def forward(self, input_ids, state, attention_mask=None, memory_lengths=None,
+ # step=None, cache=None, encoder_attention_mask=None, encoder_hidden_states=None, memory_masks=None):
+ def forward(
+ self,
+ input_ids,
+ encoder_hidden_states=None,
+ state=None,
+ attention_mask=None,
+ memory_lengths=None,
+ step=None,
+ cache=None,
+ encoder_attention_mask=None,
+ ):
+ """
+ See :obj:`onmt.modules.RNNDecoderBase.forward()`
+ memory_bank = encoder_hidden_states
+ """
+ # Name conversion
+ tgt = input_ids
+ memory_bank = encoder_hidden_states
+ memory_mask = encoder_attention_mask
+
+ # src_words = state.src
+ src_words = state.src
+ src_batch, src_len = src_words.size()
+
+ padding_idx = self.embeddings.padding_idx
+
+ # Decoder padding mask
+ tgt_words = tgt
+ tgt_batch, tgt_len = tgt_words.size()
+ tgt_pad_mask = tgt_words.data.eq(padding_idx).unsqueeze(1).expand(tgt_batch, tgt_len, tgt_len)
+
+ # Encoder padding mask
+ if memory_mask is not None:
+ src_len = memory_mask.size(-1)
+ src_pad_mask = memory_mask.expand(src_batch, tgt_len, src_len)
+ else:
+ src_pad_mask = src_words.data.eq(padding_idx).unsqueeze(1).expand(src_batch, tgt_len, src_len)
+
+ # Pass through the embeddings
+ emb = self.embeddings(input_ids)
+ output = self.pos_emb(emb, step)
+ assert emb.dim() == 3 # len x batch x embedding_dim
+
+ if state.cache is None:
+ saved_inputs = []
+
+ for i in range(self.num_layers):
+ prev_layer_input = None
+ if state.cache is None:
+ if state.previous_input is not None:
+ prev_layer_input = state.previous_layer_inputs[i]
+
+ output, all_input = self.transformer_layers[i](
+ output,
+ memory_bank,
+ src_pad_mask,
+ tgt_pad_mask,
+ previous_input=prev_layer_input,
+ layer_cache=state.cache["layer_{}".format(i)] if state.cache is not None else None,
+ step=step,
+ )
+ if state.cache is None:
+ saved_inputs.append(all_input)
+
+ if state.cache is None:
+ saved_inputs = torch.stack(saved_inputs)
+
+ output = self.layer_norm(output)
+
+ if state.cache is None:
+ state = state.update_state(tgt, saved_inputs)
+
+ # Decoders in transformers return a tuple. Beam search will fail
+ # if we don't follow this convention.
+ return output, state # , state
+
+ def init_decoder_state(self, src, memory_bank, with_cache=False):
+ """Init decoder state"""
+ state = TransformerDecoderState(src)
+ if with_cache:
+ state._init_cache(memory_bank, self.num_layers)
+ return state
+
+
+class PositionalEncoding(nn.Module):
+ def __init__(self, dropout, dim, max_len=5000):
+ pe = torch.zeros(max_len, dim)
+ position = torch.arange(0, max_len).unsqueeze(1)
+ div_term = torch.exp((torch.arange(0, dim, 2, dtype=torch.float) * -(math.log(10000.0) / dim)))
+ pe[:, 0::2] = torch.sin(position.float() * div_term)
+ pe[:, 1::2] = torch.cos(position.float() * div_term)
+ pe = pe.unsqueeze(0)
+ super().__init__()
+ self.register_buffer("pe", pe)
+ self.dropout = nn.Dropout(p=dropout)
+ self.dim = dim
+
+ def forward(self, emb, step=None):
+ emb = emb * math.sqrt(self.dim)
+ if step:
+ emb = emb + self.pe[:, step][:, None, :]
+
+ else:
+ emb = emb + self.pe[:, : emb.size(1)]
+ emb = self.dropout(emb)
+ return emb
+
+ def get_emb(self, emb):
+ return self.pe[:, : emb.size(1)]
+
+
+class TransformerDecoderLayer(nn.Module):
+ """
+ Args:
+ d_model (int): the dimension of keys/values/queries in
+ MultiHeadedAttention, also the input size of
+ the first-layer of the PositionwiseFeedForward.
+ heads (int): the number of heads for MultiHeadedAttention.
+ d_ff (int): the second-layer of the PositionwiseFeedForward.
+ dropout (float): dropout probability(0-1.0).
+ self_attn_type (string): type of self-attention scaled-dot, average
+ """
+
+ def __init__(self, d_model, heads, d_ff, dropout):
+ super().__init__()
+
+ self.self_attn = MultiHeadedAttention(heads, d_model, dropout=dropout)
+
+ self.context_attn = MultiHeadedAttention(heads, d_model, dropout=dropout)
+ self.feed_forward = PositionwiseFeedForward(d_model, d_ff, dropout)
+ self.layer_norm_1 = nn.LayerNorm(d_model, eps=1e-6)
+ self.layer_norm_2 = nn.LayerNorm(d_model, eps=1e-6)
+ self.drop = nn.Dropout(dropout)
+ mask = self._get_attn_subsequent_mask(MAX_SIZE)
+ # Register self.mask as a saved_state in TransformerDecoderLayer, so
+ # it gets TransformerDecoderLayer's cuda behavior automatically.
+ self.register_buffer("mask", mask)
+
+ def forward(
+ self,
+ inputs,
+ memory_bank,
+ src_pad_mask,
+ tgt_pad_mask,
+ previous_input=None,
+ layer_cache=None,
+ step=None,
+ ):
+ """
+ Args:
+ inputs (`FloatTensor`): `[batch_size x 1 x model_dim]`
+ memory_bank (`FloatTensor`): `[batch_size x src_len x model_dim]`
+ src_pad_mask (`LongTensor`): `[batch_size x 1 x src_len]`
+ tgt_pad_mask (`LongTensor`): `[batch_size x 1 x 1]`
+
+ Returns:
+ (`FloatTensor`, `FloatTensor`, `FloatTensor`):
+
+ * output `[batch_size x 1 x model_dim]`
+ * attn `[batch_size x 1 x src_len]`
+ * all_input `[batch_size x current_step x model_dim]`
+
+ """
+ dec_mask = torch.gt(tgt_pad_mask + self.mask[:, : tgt_pad_mask.size(1), : tgt_pad_mask.size(1)], 0)
+ input_norm = self.layer_norm_1(inputs)
+ all_input = input_norm
+ if previous_input is not None:
+ all_input = torch.cat((previous_input, input_norm), dim=1)
+ dec_mask = None
+
+ query = self.self_attn(
+ all_input,
+ all_input,
+ input_norm,
+ mask=dec_mask,
+ layer_cache=layer_cache,
+ type="self",
+ )
+
+ query = self.drop(query) + inputs
+
+ query_norm = self.layer_norm_2(query)
+ mid = self.context_attn(
+ memory_bank,
+ memory_bank,
+ query_norm,
+ mask=src_pad_mask,
+ layer_cache=layer_cache,
+ type="context",
+ )
+ output = self.feed_forward(self.drop(mid) + query)
+
+ return output, all_input
+ # return output
+
+ def _get_attn_subsequent_mask(self, size):
+ """
+ Get an attention mask to avoid using the subsequent info.
+
+ Args:
+ size: int
+
+ Returns:
+ (`LongTensor`):
+
+ * subsequent_mask `[1 x size x size]`
+ """
+ attn_shape = (1, size, size)
+ subsequent_mask = np.triu(np.ones(attn_shape), k=1).astype("uint8")
+ subsequent_mask = torch.from_numpy(subsequent_mask)
+ return subsequent_mask
+
+
+class MultiHeadedAttention(nn.Module):
+ """
+ Multi-Head Attention module from
+ "Attention is All You Need"
+ :cite:`DBLP:journals/corr/VaswaniSPUJGKP17`.
+
+ Similar to standard `dot` attention but uses
+ multiple attention distributions simulataneously
+ to select relevant items.
+
+ .. mermaid::
+
+ graph BT
+ A[key]
+ B[value]
+ C[query]
+ O[output]
+ subgraph Attn
+ D[Attn 1]
+ E[Attn 2]
+ F[Attn N]
+ end
+ A --> D
+ C --> D
+ A --> E
+ C --> E
+ A --> F
+ C --> F
+ D --> O
+ E --> O
+ F --> O
+ B --> O
+
+ Also includes several additional tricks.
+
+ Args:
+ head_count (int): number of parallel heads
+ model_dim (int): the dimension of keys/values/queries,
+ must be divisible by head_count
+ dropout (float): dropout parameter
+ """
+
+ def __init__(self, head_count, model_dim, dropout=0.1, use_final_linear=True):
+ assert model_dim % head_count == 0
+ self.dim_per_head = model_dim // head_count
+ self.model_dim = model_dim
+
+ super().__init__()
+ self.head_count = head_count
+
+ self.linear_keys = nn.Linear(model_dim, head_count * self.dim_per_head)
+ self.linear_values = nn.Linear(model_dim, head_count * self.dim_per_head)
+ self.linear_query = nn.Linear(model_dim, head_count * self.dim_per_head)
+ self.softmax = nn.Softmax(dim=-1)
+ self.dropout = nn.Dropout(dropout)
+ self.use_final_linear = use_final_linear
+ if self.use_final_linear:
+ self.final_linear = nn.Linear(model_dim, model_dim)
+
+ def forward(
+ self,
+ key,
+ value,
+ query,
+ mask=None,
+ layer_cache=None,
+ type=None,
+ predefined_graph_1=None,
+ ):
+ """
+ Compute the context vector and the attention vectors.
+
+ Args:
+ key (`FloatTensor`): set of `key_len`
+ key vectors `[batch, key_len, dim]`
+ value (`FloatTensor`): set of `key_len`
+ value vectors `[batch, key_len, dim]`
+ query (`FloatTensor`): set of `query_len`
+ query vectors `[batch, query_len, dim]`
+ mask: binary mask indicating which keys have
+ non-zero attention `[batch, query_len, key_len]`
+ Returns:
+ (`FloatTensor`, `FloatTensor`) :
+
+ * output context vectors `[batch, query_len, dim]`
+ * one of the attention vectors `[batch, query_len, key_len]`
+ """
+ batch_size = key.size(0)
+ dim_per_head = self.dim_per_head
+ head_count = self.head_count
+
+ def shape(x):
+ """projection"""
+ return x.view(batch_size, -1, head_count, dim_per_head).transpose(1, 2)
+
+ def unshape(x):
+ """compute context"""
+ return x.transpose(1, 2).contiguous().view(batch_size, -1, head_count * dim_per_head)
+
+ # 1) Project key, value, and query.
+ if layer_cache is not None:
+ if type == "self":
+ query, key, value = (
+ self.linear_query(query),
+ self.linear_keys(query),
+ self.linear_values(query),
+ )
+
+ key = shape(key)
+ value = shape(value)
+
+ if layer_cache is not None:
+ device = key.device
+ if layer_cache["self_keys"] is not None:
+ key = torch.cat((layer_cache["self_keys"].to(device), key), dim=2)
+ if layer_cache["self_values"] is not None:
+ value = torch.cat((layer_cache["self_values"].to(device), value), dim=2)
+ layer_cache["self_keys"] = key
+ layer_cache["self_values"] = value
+ elif type == "context":
+ query = self.linear_query(query)
+ if layer_cache is not None:
+ if layer_cache["memory_keys"] is None:
+ key, value = self.linear_keys(key), self.linear_values(value)
+ key = shape(key)
+ value = shape(value)
+ else:
+ key, value = (
+ layer_cache["memory_keys"],
+ layer_cache["memory_values"],
+ )
+ layer_cache["memory_keys"] = key
+ layer_cache["memory_values"] = value
+ else:
+ key, value = self.linear_keys(key), self.linear_values(value)
+ key = shape(key)
+ value = shape(value)
+ else:
+ key = self.linear_keys(key)
+ value = self.linear_values(value)
+ query = self.linear_query(query)
+ key = shape(key)
+ value = shape(value)
+
+ query = shape(query)
+
+ # 2) Calculate and scale scores.
+ query = query / math.sqrt(dim_per_head)
+ scores = torch.matmul(query, key.transpose(2, 3))
+
+ if mask is not None:
+ mask = mask.unsqueeze(1).expand_as(scores)
+ scores = scores.masked_fill(mask, -1e18)
+
+ # 3) Apply attention dropout and compute context vectors.
+
+ attn = self.softmax(scores)
+
+ if predefined_graph_1 is not None:
+ attn_masked = attn[:, -1] * predefined_graph_1
+ attn_masked = attn_masked / (torch.sum(attn_masked, 2).unsqueeze(2) + 1e-9)
+
+ attn = torch.cat([attn[:, :-1], attn_masked.unsqueeze(1)], 1)
+
+ drop_attn = self.dropout(attn)
+ if self.use_final_linear:
+ context = unshape(torch.matmul(drop_attn, value))
+ output = self.final_linear(context)
+ return output
+ else:
+ context = torch.matmul(drop_attn, value)
+ return context
+
+
+class DecoderState:
+ """Interface for grouping together the current state of a recurrent
+ decoder. In the simplest case just represents the hidden state of
+ the model. But can also be used for implementing various forms of
+ input_feeding and non-recurrent models.
+
+ Modules need to implement this to utilize beam search decoding.
+ """
+
+ def detach(self):
+ """Need to document this"""
+ self.hidden = tuple([_.detach() for _ in self.hidden])
+ self.input_feed = self.input_feed.detach()
+
+ def beam_update(self, idx, positions, beam_size):
+ """Need to document this"""
+ for e in self._all:
+ sizes = e.size()
+ br = sizes[1]
+ if len(sizes) == 3:
+ sent_states = e.view(sizes[0], beam_size, br // beam_size, sizes[2])[:, :, idx]
+ else:
+ sent_states = e.view(sizes[0], beam_size, br // beam_size, sizes[2], sizes[3])[:, :, idx]
+
+ sent_states.data.copy_(sent_states.data.index_select(1, positions))
+
+ def map_batch_fn(self, fn):
+ raise NotImplementedError()
+
+
+class TransformerDecoderState(DecoderState):
+ """Transformer Decoder state base class"""
+
+ def __init__(self, src):
+ """
+ Args:
+ src (FloatTensor): a sequence of source words tensors
+ with optional feature tensors, of size (len x batch).
+ """
+ self.src = src
+ self.previous_input = None
+ self.previous_layer_inputs = None
+ self.cache = None
+
+ @property
+ def _all(self):
+ """
+ Contains attributes that need to be updated in self.beam_update().
+ """
+ if self.previous_input is not None and self.previous_layer_inputs is not None:
+ return (self.previous_input, self.previous_layer_inputs, self.src)
+ else:
+ return (self.src,)
+
+ def detach(self):
+ if self.previous_input is not None:
+ self.previous_input = self.previous_input.detach()
+ if self.previous_layer_inputs is not None:
+ self.previous_layer_inputs = self.previous_layer_inputs.detach()
+ self.src = self.src.detach()
+
+ def update_state(self, new_input, previous_layer_inputs):
+ state = TransformerDecoderState(self.src)
+ state.previous_input = new_input
+ state.previous_layer_inputs = previous_layer_inputs
+ return state
+
+ def _init_cache(self, memory_bank, num_layers):
+ self.cache = {}
+
+ for l in range(num_layers):
+ layer_cache = {"memory_keys": None, "memory_values": None}
+ layer_cache["self_keys"] = None
+ layer_cache["self_values"] = None
+ self.cache["layer_{}".format(l)] = layer_cache
+
+ def repeat_beam_size_times(self, beam_size):
+ """Repeat beam_size times along batch dimension."""
+ self.src = self.src.data.repeat(1, beam_size, 1)
+
+ def map_batch_fn(self, fn):
+ def _recursive_map(struct, batch_dim=0):
+ for k, v in struct.items():
+ if v is not None:
+ if isinstance(v, dict):
+ _recursive_map(v)
+ else:
+ struct[k] = fn(v, batch_dim)
+
+ self.src = fn(self.src, 0)
+ if self.cache is not None:
+ _recursive_map(self.cache)
+
+
+def gelu(x):
+ return 0.5 * x * (1 + torch.tanh(math.sqrt(2 / math.pi) * (x + 0.044715 * torch.pow(x, 3))))
+
+
+class PositionwiseFeedForward(nn.Module):
+ """A two-layer Feed-Forward-Network with residual layer norm.
+
+ Args:
+ d_model (int): the size of input for the first-layer of the FFN.
+ d_ff (int): the hidden layer size of the second-layer
+ of the FNN.
+ dropout (float): dropout probability in :math:`[0, 1)`.
+ """
+
+ def __init__(self, d_model, d_ff, dropout=0.1):
+ super().__init__()
+ self.w_1 = nn.Linear(d_model, d_ff)
+ self.w_2 = nn.Linear(d_ff, d_model)
+ self.layer_norm = nn.LayerNorm(d_model, eps=1e-6)
+ self.actv = gelu
+ self.dropout_1 = nn.Dropout(dropout)
+ self.dropout_2 = nn.Dropout(dropout)
+
+ def forward(self, x):
+ inter = self.dropout_1(self.actv(self.w_1(self.layer_norm(x))))
+ output = self.dropout_2(self.w_2(inter))
+ return output + x
+
+
+#
+# TRANSLATOR
+# The following code is used to generate summaries using the
+# pre-trained weights and beam search.
+#
+
+
+def build_predictor(args, tokenizer, symbols, model, logger=None):
+ # we should be able to refactor the global scorer a lot
+ scorer = GNMTGlobalScorer(args.alpha, length_penalty="wu")
+ translator = Translator(args, model, tokenizer, symbols, global_scorer=scorer, logger=logger)
+ return translator
+
+
+class GNMTGlobalScorer:
+ """
+ NMT re-ranking score from
+ "Google's Neural Machine Translation System" :cite:`wu2016google`
+
+ Args:
+ alpha (float): length parameter
+ beta (float): coverage parameter
+ """
+
+ def __init__(self, alpha, length_penalty):
+ self.alpha = alpha
+ penalty_builder = PenaltyBuilder(length_penalty)
+ self.length_penalty = penalty_builder.length_penalty()
+
+ def score(self, beam, logprobs):
+ """
+ Rescores a prediction based on penalty functions
+ """
+ normalized_probs = self.length_penalty(beam, logprobs, self.alpha)
+ return normalized_probs
+
+
+class PenaltyBuilder:
+ """
+ Returns the Length and Coverage Penalty function for Beam Search.
+
+ Args:
+ length_pen (str): option name of length pen
+ cov_pen (str): option name of cov pen
+ """
+
+ def __init__(self, length_pen):
+ self.length_pen = length_pen
+
+ def length_penalty(self):
+ if self.length_pen == "wu":
+ return self.length_wu
+ elif self.length_pen == "avg":
+ return self.length_average
+ else:
+ return self.length_none
+
+ """
+ Below are all the different penalty terms implemented so far
+ """
+
+ def length_wu(self, beam, logprobs, alpha=0.0):
+ """
+ NMT length re-ranking score from
+ "Google's Neural Machine Translation System" :cite:`wu2016google`.
+ """
+
+ modifier = ((5 + len(beam.next_ys)) ** alpha) / ((5 + 1) ** alpha)
+ return logprobs / modifier
+
+ def length_average(self, beam, logprobs, alpha=0.0):
+ """
+ Returns the average probability of tokens in a sequence.
+ """
+ return logprobs / len(beam.next_ys)
+
+ def length_none(self, beam, logprobs, alpha=0.0, beta=0.0):
+ """
+ Returns unmodified scores.
+ """
+ return logprobs
+
+
+class Translator:
+ """
+ Uses a model to translate a batch of sentences.
+
+ Args:
+ model (:obj:`onmt.modules.NMTModel`):
+ NMT model to use for translation
+ fields (dict of Fields): data fields
+ beam_size (int): size of beam to use
+ n_best (int): number of translations produced
+ max_length (int): maximum length output to produce
+ global_scores (:obj:`GlobalScorer`):
+ object to rescore final translations
+ copy_attn (bool): use copy attention during translation
+ beam_trace (bool): trace beam search for debugging
+ logger(logging.Logger): logger.
+ """
+
+ def __init__(self, args, model, vocab, symbols, global_scorer=None, logger=None):
+ self.logger = logger
+
+ self.args = args
+ self.model = model
+ self.generator = self.model.generator
+ self.vocab = vocab
+ self.symbols = symbols
+ self.start_token = symbols["BOS"]
+ self.end_token = symbols["EOS"]
+
+ self.global_scorer = global_scorer
+ self.beam_size = args.beam_size
+ self.min_length = args.min_length
+ self.max_length = args.max_length
+
+ def translate(self, batch, step, attn_debug=False):
+ """Generates summaries from one batch of data."""
+ self.model.eval()
+ with torch.no_grad():
+ batch_data = self.translate_batch(batch)
+ translations = self.from_batch(batch_data)
+ return translations
+
+ def translate_batch(self, batch, fast=False):
+ """
+ Translate a batch of sentences.
+
+ Mostly a wrapper around :obj:`Beam`.
+
+ Args:
+ batch (:obj:`Batch`): a batch from a dataset object
+ fast (bool): enables fast beam search (may not support all features)
+ """
+ with torch.no_grad():
+ return self._fast_translate_batch(batch, self.max_length, min_length=self.min_length)
+
+ # Where the beam search lives
+ # I have no idea why it is being called from the method above
+ def _fast_translate_batch(self, batch, max_length, min_length=0):
+ """Beam Search using the encoder inputs contained in `batch`."""
+
+ # The batch object is funny
+ # Instead of just looking at the size of the arguments we encapsulate
+ # a size argument.
+ # Where is it defined?
+ beam_size = self.beam_size
+ batch_size = batch.batch_size
+ src = batch.src
+ segs = batch.segs
+ mask_src = batch.mask_src
+
+ src_features = self.model.bert(src, segs, mask_src)
+ dec_states = self.model.decoder.init_decoder_state(src, src_features, with_cache=True)
+ device = src_features.device
+
+ # Tile states and memory beam_size times.
+ dec_states.map_batch_fn(lambda state, dim: tile(state, beam_size, dim=dim))
+ src_features = tile(src_features, beam_size, dim=0)
+ batch_offset = torch.arange(batch_size, dtype=torch.long, device=device)
+ beam_offset = torch.arange(0, batch_size * beam_size, step=beam_size, dtype=torch.long, device=device)
+ alive_seq = torch.full([batch_size * beam_size, 1], self.start_token, dtype=torch.long, device=device)
+
+ # Give full probability to the first beam on the first step.
+ topk_log_probs = torch.tensor([0.0] + [float("-inf")] * (beam_size - 1), device=device).repeat(batch_size)
+
+ # Structure that holds finished hypotheses.
+ hypotheses = [[] for _ in range(batch_size)] # noqa: F812
+
+ results = {}
+ results["predictions"] = [[] for _ in range(batch_size)] # noqa: F812
+ results["scores"] = [[] for _ in range(batch_size)] # noqa: F812
+ results["gold_score"] = [0] * batch_size
+ results["batch"] = batch
+
+ for step in range(max_length):
+ decoder_input = alive_seq[:, -1].view(1, -1)
+
+ # Decoder forward.
+ decoder_input = decoder_input.transpose(0, 1)
+
+ dec_out, dec_states = self.model.decoder(decoder_input, src_features, dec_states, step=step)
+
+ # Generator forward.
+ log_probs = self.generator(dec_out.transpose(0, 1).squeeze(0))
+ vocab_size = log_probs.size(-1)
+
+ if step < min_length:
+ log_probs[:, self.end_token] = -1e20
+
+ # Multiply probs by the beam probability.
+ log_probs += topk_log_probs.view(-1).unsqueeze(1)
+
+ alpha = self.global_scorer.alpha
+ length_penalty = ((5.0 + (step + 1)) / 6.0) ** alpha
+
+ # Flatten probs into a list of possibilities.
+ curr_scores = log_probs / length_penalty
+
+ if self.args.block_trigram:
+ cur_len = alive_seq.size(1)
+ if cur_len > 3:
+ for i in range(alive_seq.size(0)):
+ fail = False
+ words = [int(w) for w in alive_seq[i]]
+ words = [self.vocab.ids_to_tokens[w] for w in words]
+ words = " ".join(words).replace(" ##", "").split()
+ if len(words) <= 3:
+ continue
+ trigrams = [(words[i - 1], words[i], words[i + 1]) for i in range(1, len(words) - 1)]
+ trigram = tuple(trigrams[-1])
+ if trigram in trigrams[:-1]:
+ fail = True
+ if fail:
+ curr_scores[i] = -10e20
+
+ curr_scores = curr_scores.reshape(-1, beam_size * vocab_size)
+ topk_scores, topk_ids = curr_scores.topk(beam_size, dim=-1)
+
+ # Recover log probs.
+ topk_log_probs = topk_scores * length_penalty
+
+ # Resolve beam origin and true word ids.
+ topk_beam_index = topk_ids.div(vocab_size)
+ topk_ids = topk_ids.fmod(vocab_size)
+
+ # Map beam_index to batch_index in the flat representation.
+ batch_index = topk_beam_index + beam_offset[: topk_beam_index.size(0)].unsqueeze(1)
+ select_indices = batch_index.view(-1)
+
+ # Append last prediction.
+ alive_seq = torch.cat([alive_seq.index_select(0, select_indices), topk_ids.view(-1, 1)], -1)
+
+ is_finished = topk_ids.eq(self.end_token)
+ if step + 1 == max_length:
+ is_finished.fill_(1)
+ # End condition is top beam is finished.
+ end_condition = is_finished[:, 0].eq(1)
+ # Save finished hypotheses.
+ if is_finished.any():
+ predictions = alive_seq.view(-1, beam_size, alive_seq.size(-1))
+ for i in range(is_finished.size(0)):
+ b = batch_offset[i]
+ if end_condition[i]:
+ is_finished[i].fill_(1)
+ finished_hyp = is_finished[i].nonzero().view(-1)
+ # Store finished hypotheses for this batch.
+ for j in finished_hyp:
+ hypotheses[b].append((topk_scores[i, j], predictions[i, j, 1:]))
+ # If the batch reached the end, save the n_best hypotheses.
+ if end_condition[i]:
+ best_hyp = sorted(hypotheses[b], key=lambda x: x[0], reverse=True)
+ score, pred = best_hyp[0]
+
+ results["scores"][b].append(score)
+ results["predictions"][b].append(pred)
+ non_finished = end_condition.eq(0).nonzero().view(-1)
+ # If all sentences are translated, no need to go further.
+ if len(non_finished) == 0:
+ break
+ # Remove finished batches for the next step.
+ topk_log_probs = topk_log_probs.index_select(0, non_finished)
+ batch_index = batch_index.index_select(0, non_finished)
+ batch_offset = batch_offset.index_select(0, non_finished)
+ alive_seq = predictions.index_select(0, non_finished).view(-1, alive_seq.size(-1))
+ # Reorder states.
+ select_indices = batch_index.view(-1)
+ src_features = src_features.index_select(0, select_indices)
+ dec_states.map_batch_fn(lambda state, dim: state.index_select(dim, select_indices))
+
+ return results
+
+ def from_batch(self, translation_batch):
+ batch = translation_batch["batch"]
+ assert len(translation_batch["gold_score"]) == len(translation_batch["predictions"])
+ batch_size = batch.batch_size
+
+ preds, _, _, tgt_str, src = (
+ translation_batch["predictions"],
+ translation_batch["scores"],
+ translation_batch["gold_score"],
+ batch.tgt_str,
+ batch.src,
+ )
+
+ translations = []
+ for b in range(batch_size):
+ pred_sents = self.vocab.convert_ids_to_tokens([int(n) for n in preds[b][0]])
+ pred_sents = " ".join(pred_sents).replace(" ##", "")
+ gold_sent = " ".join(tgt_str[b].split())
+ raw_src = [self.vocab.ids_to_tokens[int(t)] for t in src[b]][:500]
+ raw_src = " ".join(raw_src)
+ translation = (pred_sents, gold_sent, raw_src)
+ translations.append(translation)
+
+ return translations
+
+
+def tile(x, count, dim=0):
+ """
+ Tiles x on dimension dim count times.
+ """
+ perm = list(range(len(x.size())))
+ if dim != 0:
+ perm[0], perm[dim] = perm[dim], perm[0]
+ x = x.permute(perm).contiguous()
+ out_size = list(x.size())
+ out_size[0] *= count
+ batch = x.size(0)
+ x = x.view(batch, -1).transpose(0, 1).repeat(count, 1).transpose(0, 1).contiguous().view(*out_size)
+ if dim != 0:
+ x = x.permute(perm).contiguous()
+ return x
+
+
+#
+# Optimizer for training. We keep this here in case we want to add
+# a finetuning script.
+#
+
+
+class BertSumOptimizer:
+ """Specific optimizer for BertSum.
+
+ As described in [1], the authors fine-tune BertSum for abstractive
+ summarization using two Adam Optimizers with different warm-up steps and
+ learning rate. They also use a custom learning rate scheduler.
+
+ [1] Liu, Yang, and Mirella Lapata. "Text summarization with pretrained encoders."
+ arXiv preprint arXiv:1908.08345 (2019).
+ """
+
+ def __init__(self, model, lr, warmup_steps, beta_1=0.99, beta_2=0.999, eps=1e-8):
+ self.encoder = model.encoder
+ self.decoder = model.decoder
+ self.lr = lr
+ self.warmup_steps = warmup_steps
+
+ self.optimizers = {
+ "encoder": torch.optim.Adam(
+ model.encoder.parameters(),
+ lr=lr["encoder"],
+ betas=(beta_1, beta_2),
+ eps=eps,
+ ),
+ "decoder": torch.optim.Adam(
+ model.decoder.parameters(),
+ lr=lr["decoder"],
+ betas=(beta_1, beta_2),
+ eps=eps,
+ ),
+ }
+
+ self._step = 0
+ self.current_learning_rates = {}
+
+ def _update_rate(self, stack):
+ return self.lr[stack] * min(self._step ** (-0.5), self._step * self.warmup_steps[stack] ** (-1.5))
+
+ def zero_grad(self):
+ self.optimizer_decoder.zero_grad()
+ self.optimizer_encoder.zero_grad()
+
+ def step(self):
+ self._step += 1
+ for stack, optimizer in self.optimizers.items():
+ new_rate = self._update_rate(stack)
+ for param_group in optimizer.param_groups:
+ param_group["lr"] = new_rate
+ optimizer.step()
+ self.current_learning_rates[stack] = new_rate
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..bc2a3d6a163005ad3d4f2817a7ca3985c87a9f1b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/requirements.txt
@@ -0,0 +1,5 @@
+transformers == 4.38.0
+
+# For ROUGE
+nltk
+py-rouge
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/run_summarization.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/run_summarization.py
new file mode 100644
index 0000000000000000000000000000000000000000..1f969f117baaf21cea56f2dfc5371b91b9fd1962
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/run_summarization.py
@@ -0,0 +1,347 @@
+#! /usr/bin/python3
+import argparse
+import logging
+import os
+import sys
+from collections import namedtuple
+
+import torch
+from modeling_bertabs import BertAbs, build_predictor
+from torch.utils.data import DataLoader, SequentialSampler
+from tqdm import tqdm
+
+from transformers import BertTokenizer
+
+from .utils_summarization import (
+ CNNDMDataset,
+ build_mask,
+ compute_token_type_ids,
+ encode_for_summarization,
+ truncate_or_pad,
+)
+
+
+logger = logging.getLogger(__name__)
+logging.basicConfig(stream=sys.stdout, level=logging.INFO)
+
+
+Batch = namedtuple("Batch", ["document_names", "batch_size", "src", "segs", "mask_src", "tgt_str"])
+
+
+def evaluate(args):
+ tokenizer = BertTokenizer.from_pretrained("google-bert/bert-base-uncased", do_lower_case=True)
+ model = BertAbs.from_pretrained("remi/bertabs-finetuned-extractive-abstractive-summarization")
+ model.to(args.device)
+ model.eval()
+
+ symbols = {
+ "BOS": tokenizer.vocab["[unused0]"],
+ "EOS": tokenizer.vocab["[unused1]"],
+ "PAD": tokenizer.vocab["[PAD]"],
+ }
+
+ if args.compute_rouge:
+ reference_summaries = []
+ generated_summaries = []
+
+ import nltk
+ import rouge
+
+ nltk.download("punkt")
+ rouge_evaluator = rouge.Rouge(
+ metrics=["rouge-n", "rouge-l"],
+ max_n=2,
+ limit_length=True,
+ length_limit=args.beam_size,
+ length_limit_type="words",
+ apply_avg=True,
+ apply_best=False,
+ alpha=0.5, # Default F1_score
+ weight_factor=1.2,
+ stemming=True,
+ )
+
+ # these (unused) arguments are defined to keep the compatibility
+ # with the legacy code and will be deleted in a next iteration.
+ args.result_path = ""
+ args.temp_dir = ""
+
+ data_iterator = build_data_iterator(args, tokenizer)
+ predictor = build_predictor(args, tokenizer, symbols, model)
+
+ logger.info("***** Running evaluation *****")
+ logger.info(" Number examples = %d", len(data_iterator.dataset))
+ logger.info(" Batch size = %d", args.batch_size)
+ logger.info("")
+ logger.info("***** Beam Search parameters *****")
+ logger.info(" Beam size = %d", args.beam_size)
+ logger.info(" Minimum length = %d", args.min_length)
+ logger.info(" Maximum length = %d", args.max_length)
+ logger.info(" Alpha (length penalty) = %.2f", args.alpha)
+ logger.info(" Trigrams %s be blocked", ("will" if args.block_trigram else "will NOT"))
+
+ for batch in tqdm(data_iterator):
+ batch_data = predictor.translate_batch(batch)
+ translations = predictor.from_batch(batch_data)
+ summaries = [format_summary(t) for t in translations]
+ save_summaries(summaries, args.summaries_output_dir, batch.document_names)
+
+ if args.compute_rouge:
+ reference_summaries += batch.tgt_str
+ generated_summaries += summaries
+
+ if args.compute_rouge:
+ scores = rouge_evaluator.get_scores(generated_summaries, reference_summaries)
+ str_scores = format_rouge_scores(scores)
+ save_rouge_scores(str_scores)
+ print(str_scores)
+
+
+def save_summaries(summaries, path, original_document_name):
+ """Write the summaries in fies that are prefixed by the original
+ files' name with the `_summary` appended.
+
+ Attributes:
+ original_document_names: List[string]
+ Name of the document that was summarized.
+ path: string
+ Path were the summaries will be written
+ summaries: List[string]
+ The summaries that we produced.
+ """
+ for summary, document_name in zip(summaries, original_document_name):
+ # Prepare the summary file's name
+ if "." in document_name:
+ bare_document_name = ".".join(document_name.split(".")[:-1])
+ extension = document_name.split(".")[-1]
+ name = bare_document_name + "_summary." + extension
+ else:
+ name = document_name + "_summary"
+
+ file_path = os.path.join(path, name)
+ with open(file_path, "w") as output:
+ output.write(summary)
+
+
+def format_summary(translation):
+ """Transforms the output of the `from_batch` function
+ into nicely formatted summaries.
+ """
+ raw_summary, _, _ = translation
+ summary = (
+ raw_summary.replace("[unused0]", "")
+ .replace("[unused3]", "")
+ .replace("[PAD]", "")
+ .replace("[unused1]", "")
+ .replace(r" +", " ")
+ .replace(" [unused2] ", ". ")
+ .replace("[unused2]", "")
+ .strip()
+ )
+
+ return summary
+
+
+def format_rouge_scores(scores):
+ return """\n
+****** ROUGE SCORES ******
+
+** ROUGE 1
+F1 >> {:.3f}
+Precision >> {:.3f}
+Recall >> {:.3f}
+
+** ROUGE 2
+F1 >> {:.3f}
+Precision >> {:.3f}
+Recall >> {:.3f}
+
+** ROUGE L
+F1 >> {:.3f}
+Precision >> {:.3f}
+Recall >> {:.3f}""".format(
+ scores["rouge-1"]["f"],
+ scores["rouge-1"]["p"],
+ scores["rouge-1"]["r"],
+ scores["rouge-2"]["f"],
+ scores["rouge-2"]["p"],
+ scores["rouge-2"]["r"],
+ scores["rouge-l"]["f"],
+ scores["rouge-l"]["p"],
+ scores["rouge-l"]["r"],
+ )
+
+
+def save_rouge_scores(str_scores):
+ with open("rouge_scores.txt", "w") as output:
+ output.write(str_scores)
+
+
+#
+# LOAD the dataset
+#
+
+
+def build_data_iterator(args, tokenizer):
+ dataset = load_and_cache_examples(args, tokenizer)
+ sampler = SequentialSampler(dataset)
+
+ def collate_fn(data):
+ return collate(data, tokenizer, block_size=512, device=args.device)
+
+ iterator = DataLoader(
+ dataset,
+ sampler=sampler,
+ batch_size=args.batch_size,
+ collate_fn=collate_fn,
+ )
+
+ return iterator
+
+
+def load_and_cache_examples(args, tokenizer):
+ dataset = CNNDMDataset(args.documents_dir)
+ return dataset
+
+
+def collate(data, tokenizer, block_size, device):
+ """Collate formats the data passed to the data loader.
+
+ In particular we tokenize the data batch after batch to avoid keeping them
+ all in memory. We output the data as a namedtuple to fit the original BertAbs's
+ API.
+ """
+ data = [x for x in data if not len(x[1]) == 0] # remove empty_files
+ names = [name for name, _, _ in data]
+ summaries = [" ".join(summary_list) for _, _, summary_list in data]
+
+ encoded_text = [encode_for_summarization(story, summary, tokenizer) for _, story, summary in data]
+ encoded_stories = torch.tensor(
+ [truncate_or_pad(story, block_size, tokenizer.pad_token_id) for story, _ in encoded_text]
+ )
+ encoder_token_type_ids = compute_token_type_ids(encoded_stories, tokenizer.cls_token_id)
+ encoder_mask = build_mask(encoded_stories, tokenizer.pad_token_id)
+
+ batch = Batch(
+ document_names=names,
+ batch_size=len(encoded_stories),
+ src=encoded_stories.to(device),
+ segs=encoder_token_type_ids.to(device),
+ mask_src=encoder_mask.to(device),
+ tgt_str=summaries,
+ )
+
+ return batch
+
+
+def decode_summary(summary_tokens, tokenizer):
+ """Decode the summary and return it in a format
+ suitable for evaluation.
+ """
+ summary_tokens = summary_tokens.to("cpu").numpy()
+ summary = tokenizer.decode(summary_tokens)
+ sentences = summary.split(".")
+ sentences = [s + "." for s in sentences]
+ return sentences
+
+
+def main():
+ """The main function defines the interface with the users."""
+ parser = argparse.ArgumentParser()
+ parser.add_argument(
+ "--documents_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The folder where the documents to summarize are located.",
+ )
+ parser.add_argument(
+ "--summaries_output_dir",
+ default=None,
+ type=str,
+ required=False,
+ help="The folder in wich the summaries should be written. Defaults to the folder where the documents are",
+ )
+ parser.add_argument(
+ "--compute_rouge",
+ default=False,
+ type=bool,
+ required=False,
+ help="Compute the ROUGE metrics during evaluation. Only available for the CNN/DailyMail dataset.",
+ )
+ # EVALUATION options
+ parser.add_argument(
+ "--no_cuda",
+ default=False,
+ type=bool,
+ help="Whether to force the execution on CPU.",
+ )
+ parser.add_argument(
+ "--batch_size",
+ default=4,
+ type=int,
+ help="Batch size per GPU/CPU for training.",
+ )
+ # BEAM SEARCH arguments
+ parser.add_argument(
+ "--min_length",
+ default=50,
+ type=int,
+ help="Minimum number of tokens for the summaries.",
+ )
+ parser.add_argument(
+ "--max_length",
+ default=200,
+ type=int,
+ help="Maixmum number of tokens for the summaries.",
+ )
+ parser.add_argument(
+ "--beam_size",
+ default=5,
+ type=int,
+ help="The number of beams to start with for each example.",
+ )
+ parser.add_argument(
+ "--alpha",
+ default=0.95,
+ type=float,
+ help="The value of alpha for the length penalty in the beam search.",
+ )
+ parser.add_argument(
+ "--block_trigram",
+ default=True,
+ type=bool,
+ help="Whether to block the existence of repeating trigrams in the text generated by beam search.",
+ )
+ args = parser.parse_args()
+
+ # Select device (distibuted not available)
+ args.device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
+
+ # Check the existence of directories
+ if not args.summaries_output_dir:
+ args.summaries_output_dir = args.documents_dir
+
+ if not documents_dir_is_valid(args.documents_dir):
+ raise FileNotFoundError(
+ "We could not find the directory you specified for the documents to summarize, or it was empty. Please"
+ " specify a valid path."
+ )
+ os.makedirs(args.summaries_output_dir, exist_ok=True)
+
+ evaluate(args)
+
+
+def documents_dir_is_valid(path):
+ if not os.path.exists(path):
+ return False
+
+ file_list = os.listdir(path)
+ if len(file_list) == 0:
+ return False
+
+ return True
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/test_utils_summarization.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/test_utils_summarization.py
new file mode 100644
index 0000000000000000000000000000000000000000..18120c9063edaf95a4896d11e84a22d1b51882dd
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/test_utils_summarization.py
@@ -0,0 +1,98 @@
+# coding=utf-8
+# Copyright 2019 HuggingFace Inc.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import unittest
+
+import numpy as np
+import torch
+
+from .utils_summarization import build_mask, compute_token_type_ids, process_story, truncate_or_pad
+
+
+class SummarizationDataProcessingTest(unittest.TestCase):
+ def setUp(self):
+ self.block_size = 10
+
+ def test_fit_to_block_sequence_too_small(self):
+ """Pad the sequence with 0 if the sequence is smaller than the block size."""
+ sequence = [1, 2, 3, 4]
+ expected_output = [1, 2, 3, 4, 0, 0, 0, 0, 0, 0]
+ self.assertEqual(truncate_or_pad(sequence, self.block_size, 0), expected_output)
+
+ def test_fit_to_block_sequence_fit_exactly(self):
+ """Do nothing if the sequence is the right size."""
+ sequence = [1, 2, 3, 4, 5, 6, 7, 8, 9, 10]
+ expected_output = [1, 2, 3, 4, 5, 6, 7, 8, 9, 10]
+ self.assertEqual(truncate_or_pad(sequence, self.block_size, 0), expected_output)
+
+ def test_fit_to_block_sequence_too_big(self):
+ """Truncate the sequence if it is too long."""
+ sequence = [1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13]
+ expected_output = [1, 2, 3, 4, 5, 6, 7, 8, 9, 10]
+ self.assertEqual(truncate_or_pad(sequence, self.block_size, 0), expected_output)
+
+ def test_process_story_no_highlights(self):
+ """Processing a story with no highlights returns an empty list for the summary."""
+ raw_story = """It was the year of Our Lord one thousand seven hundred and
+ seventy-five.\n\nSpiritual revelations were conceded to England at that
+ favoured period, as at this."""
+ _, summary_lines = process_story(raw_story)
+ self.assertEqual(summary_lines, [])
+
+ def test_process_empty_story(self):
+ """An empty story returns an empty collection of lines."""
+ raw_story = ""
+ story_lines, summary_lines = process_story(raw_story)
+ self.assertEqual(story_lines, [])
+ self.assertEqual(summary_lines, [])
+
+ def test_process_story_with_missing_period(self):
+ raw_story = (
+ "It was the year of Our Lord one thousand seven hundred and "
+ "seventy-five\n\nSpiritual revelations were conceded to England "
+ "at that favoured period, as at this.\n@highlight\n\nIt was the best of times"
+ )
+ story_lines, summary_lines = process_story(raw_story)
+
+ expected_story_lines = [
+ "It was the year of Our Lord one thousand seven hundred and seventy-five.",
+ "Spiritual revelations were conceded to England at that favoured period, as at this.",
+ ]
+ self.assertEqual(expected_story_lines, story_lines)
+
+ expected_summary_lines = ["It was the best of times."]
+ self.assertEqual(expected_summary_lines, summary_lines)
+
+ def test_build_mask_no_padding(self):
+ sequence = torch.tensor([1, 2, 3, 4])
+ expected = torch.tensor([1, 1, 1, 1])
+ np.testing.assert_array_equal(build_mask(sequence, 0).numpy(), expected.numpy())
+
+ def test_build_mask(self):
+ sequence = torch.tensor([1, 2, 3, 4, 23, 23, 23])
+ expected = torch.tensor([1, 1, 1, 1, 0, 0, 0])
+ np.testing.assert_array_equal(build_mask(sequence, 23).numpy(), expected.numpy())
+
+ def test_build_mask_with_padding_equal_to_one(self):
+ sequence = torch.tensor([8, 2, 3, 4, 1, 1, 1])
+ expected = torch.tensor([1, 1, 1, 1, 0, 0, 0])
+ np.testing.assert_array_equal(build_mask(sequence, 1).numpy(), expected.numpy())
+
+ def test_compute_token_type_ids(self):
+ separator = 101
+ batch = torch.tensor([[1, 2, 3, 4, 5, 6], [1, 2, 3, 101, 5, 6], [1, 101, 3, 4, 101, 6]])
+ expected = torch.tensor([[1, 1, 1, 1, 1, 1], [1, 1, 1, 0, 0, 0], [1, 0, 0, 0, 1, 1]])
+
+ result = compute_token_type_ids(batch, separator)
+ np.testing.assert_array_equal(result, expected)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/utils_summarization.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/utils_summarization.py
new file mode 100644
index 0000000000000000000000000000000000000000..716365336bb5393dd496e8541a773b9a1951ca01
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertabs/utils_summarization.py
@@ -0,0 +1,167 @@
+import os
+from collections import deque
+
+import torch
+from torch.utils.data import Dataset
+
+
+# ------------
+# Data loading
+# ------------
+
+
+class CNNDMDataset(Dataset):
+ """Abstracts the dataset used to train seq2seq models.
+
+ The class will process the documents that are located in the specified
+ folder. The preprocessing will work on any document that is reasonably
+ formatted. On the CNN/DailyMail dataset it will extract both the story
+ and the summary.
+
+ CNN/Daily News:
+
+ The CNN/Daily News raw datasets are downloaded from [1]. The stories are
+ stored in different files; the summary appears at the end of the story as
+ sentences that are prefixed by the special `@highlight` line. To process
+ the data, untar both datasets in the same folder, and pass the path to this
+ folder as the "data_dir argument. The formatting code was inspired by [2].
+
+ [1] https://cs.nyu.edu/~kcho/
+ [2] https://github.com/abisee/cnn-dailymail/
+ """
+
+ def __init__(self, path="", prefix="train"):
+ """We initialize the class by listing all the documents to summarize.
+ Files are not read in memory due to the size of some datasets (like CNN/DailyMail).
+ """
+ assert os.path.isdir(path)
+
+ self.documents = []
+ story_filenames_list = os.listdir(path)
+ for story_filename in story_filenames_list:
+ if "summary" in story_filename:
+ continue
+ path_to_story = os.path.join(path, story_filename)
+ if not os.path.isfile(path_to_story):
+ continue
+ self.documents.append(path_to_story)
+
+ def __len__(self):
+ """Returns the number of documents."""
+ return len(self.documents)
+
+ def __getitem__(self, idx):
+ document_path = self.documents[idx]
+ document_name = document_path.split("/")[-1]
+ with open(document_path, encoding="utf-8") as source:
+ raw_story = source.read()
+ story_lines, summary_lines = process_story(raw_story)
+ return document_name, story_lines, summary_lines
+
+
+def process_story(raw_story):
+ """Extract the story and summary from a story file.
+
+ Arguments:
+ raw_story (str): content of the story file as an utf-8 encoded string.
+
+ Raises:
+ IndexError: If the story is empty or contains no highlights.
+ """
+ nonempty_lines = list(filter(lambda x: len(x) != 0, [line.strip() for line in raw_story.split("\n")]))
+
+ # for some unknown reason some lines miss a period, add it
+ nonempty_lines = [_add_missing_period(line) for line in nonempty_lines]
+
+ # gather article lines
+ story_lines = []
+ lines = deque(nonempty_lines)
+ while True:
+ try:
+ element = lines.popleft()
+ if element.startswith("@highlight"):
+ break
+ story_lines.append(element)
+ except IndexError:
+ # if "@highlight" is absent from the file we pop
+ # all elements until there is None, raising an exception.
+ return story_lines, []
+
+ # gather summary lines
+ summary_lines = list(filter(lambda t: not t.startswith("@highlight"), lines))
+
+ return story_lines, summary_lines
+
+
+def _add_missing_period(line):
+ END_TOKENS = [".", "!", "?", "...", "'", "`", '"', "\u2019", "\u2019", ")"]
+ if line.startswith("@highlight"):
+ return line
+ if line[-1] in END_TOKENS:
+ return line
+ return line + "."
+
+
+# --------------------------
+# Encoding and preprocessing
+# --------------------------
+
+
+def truncate_or_pad(sequence, block_size, pad_token_id):
+ """Adapt the source and target sequences' lengths to the block size.
+ If the sequence is shorter we append padding token to the right of the sequence.
+ """
+ if len(sequence) > block_size:
+ return sequence[:block_size]
+ else:
+ sequence.extend([pad_token_id] * (block_size - len(sequence)))
+ return sequence
+
+
+def build_mask(sequence, pad_token_id):
+ """Builds the mask. The attention mechanism will only attend to positions
+ with value 1."""
+ mask = torch.ones_like(sequence)
+ idx_pad_tokens = sequence == pad_token_id
+ mask[idx_pad_tokens] = 0
+ return mask
+
+
+def encode_for_summarization(story_lines, summary_lines, tokenizer):
+ """Encode the story and summary lines, and join them
+ as specified in [1] by using `[SEP] [CLS]` tokens to separate
+ sentences.
+ """
+ story_lines_token_ids = [tokenizer.encode(line) for line in story_lines]
+ story_token_ids = [token for sentence in story_lines_token_ids for token in sentence]
+ summary_lines_token_ids = [tokenizer.encode(line) for line in summary_lines]
+ summary_token_ids = [token for sentence in summary_lines_token_ids for token in sentence]
+
+ return story_token_ids, summary_token_ids
+
+
+def compute_token_type_ids(batch, separator_token_id):
+ """Segment embeddings as described in [1]
+
+ The values {0,1} were found in the repository [2].
+
+ Attributes:
+ batch: torch.Tensor, size [batch_size, block_size]
+ Batch of input.
+ separator_token_id: int
+ The value of the token that separates the segments.
+
+ [1] Liu, Yang, and Mirella Lapata. "Text summarization with pretrained encoders."
+ arXiv preprint arXiv:1908.08345 (2019).
+ [2] https://github.com/nlpyang/PreSumm (/src/prepro/data_builder.py, commit fac1217)
+ """
+ batch_embeddings = []
+ for sequence in batch:
+ sentence_num = -1
+ embeddings = []
+ for s in sequence:
+ if s == separator_token_id:
+ sentence_num += 1
+ embeddings.append(sentence_num % 2)
+ batch_embeddings.append(embeddings)
+ return torch.tensor(batch_embeddings)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertology/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertology/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..99636a7fce1b8ebdd049db2bdeb2248c02791fce
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertology/requirements.txt
@@ -0,0 +1 @@
+transformers == 4.38.0
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertology/run_bertology.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertology/run_bertology.py
new file mode 100644
index 0000000000000000000000000000000000000000..35d096f164991553f39e1e70e2074e6aaa179f72
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertology/run_bertology.py
@@ -0,0 +1,453 @@
+#!/usr/bin/env python3
+# Copyright 2018 CMU and The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Bertology: this script shows how you can explore the internals of the models in the library to:
+- compute the entropy of the head attentions
+- compute the importance of each head
+- prune (remove) the low importance head.
+Some parts of this script are adapted from the code of Michel et al. (http://arxiv.org/abs/1905.10650)
+which is available at https://github.com/pmichel31415/are-16-heads-really-better-than-1
+"""
+
+import argparse
+import logging
+import os
+from datetime import datetime
+
+import numpy as np
+import torch
+from torch import nn
+from torch.utils.data import DataLoader, SequentialSampler, Subset
+from torch.utils.data.distributed import DistributedSampler
+from tqdm import tqdm
+
+import transformers
+from transformers import (
+ AutoConfig,
+ AutoModelForSequenceClassification,
+ AutoTokenizer,
+ GlueDataset,
+ default_data_collator,
+ glue_compute_metrics,
+ glue_output_modes,
+ glue_processors,
+ set_seed,
+)
+from transformers.trainer_utils import is_main_process
+
+
+logger = logging.getLogger(__name__)
+
+
+def entropy(p):
+ """Compute the entropy of a probability distribution"""
+ plogp = p * torch.log(p)
+ plogp[p == 0] = 0
+ return -plogp.sum(dim=-1)
+
+
+def print_2d_tensor(tensor):
+ """Print a 2D tensor"""
+ logger.info("lv, h >\t" + "\t".join(f"{x + 1}" for x in range(len(tensor))))
+ for row in range(len(tensor)):
+ if tensor.dtype != torch.long:
+ logger.info(f"layer {row + 1}:\t" + "\t".join(f"{x:.5f}" for x in tensor[row].cpu().data))
+ else:
+ logger.info(f"layer {row + 1}:\t" + "\t".join(f"{x:d}" for x in tensor[row].cpu().data))
+
+
+def compute_heads_importance(
+ args, model, eval_dataloader, compute_entropy=True, compute_importance=True, head_mask=None, actually_pruned=False
+):
+ """This method shows how to compute:
+ - head attention entropy
+ - head importance scores according to http://arxiv.org/abs/1905.10650
+ """
+ # Prepare our tensors
+ n_layers, n_heads = model.config.num_hidden_layers, model.config.num_attention_heads
+ head_importance = torch.zeros(n_layers, n_heads).to(args.device)
+ attn_entropy = torch.zeros(n_layers, n_heads).to(args.device)
+
+ if head_mask is None:
+ head_mask = torch.ones(n_layers, n_heads).to(args.device)
+
+ head_mask.requires_grad_(requires_grad=True)
+ # If actually pruned attention multi-head, set head mask to None to avoid shape mismatch
+ if actually_pruned:
+ head_mask = None
+
+ preds = None
+ labels = None
+ tot_tokens = 0.0
+
+ for step, inputs in enumerate(tqdm(eval_dataloader, desc="Iteration", disable=args.local_rank not in [-1, 0])):
+ for k, v in inputs.items():
+ inputs[k] = v.to(args.device)
+
+ # Do a forward pass (not with torch.no_grad() since we need gradients for importance score - see below)
+ outputs = model(**inputs, head_mask=head_mask)
+ loss, logits, all_attentions = (
+ outputs[0],
+ outputs[1],
+ outputs[-1],
+ ) # Loss and logits are the first, attention the last
+ loss.backward() # Backpropagate to populate the gradients in the head mask
+
+ if compute_entropy:
+ for layer, attn in enumerate(all_attentions):
+ masked_entropy = entropy(attn.detach()) * inputs["attention_mask"].float().unsqueeze(1)
+ attn_entropy[layer] += masked_entropy.sum(-1).sum(0).detach()
+
+ if compute_importance:
+ head_importance += head_mask.grad.abs().detach()
+
+ # Also store our logits/labels if we want to compute metrics afterwards
+ if preds is None:
+ preds = logits.detach().cpu().numpy()
+ labels = inputs["labels"].detach().cpu().numpy()
+ else:
+ preds = np.append(preds, logits.detach().cpu().numpy(), axis=0)
+ labels = np.append(labels, inputs["labels"].detach().cpu().numpy(), axis=0)
+
+ tot_tokens += inputs["attention_mask"].float().detach().sum().data
+
+ # Normalize
+ attn_entropy /= tot_tokens
+ head_importance /= tot_tokens
+ # Layerwise importance normalization
+ if not args.dont_normalize_importance_by_layer:
+ exponent = 2
+ norm_by_layer = torch.pow(torch.pow(head_importance, exponent).sum(-1), 1 / exponent)
+ head_importance /= norm_by_layer.unsqueeze(-1) + 1e-20
+
+ if not args.dont_normalize_global_importance:
+ head_importance = (head_importance - head_importance.min()) / (head_importance.max() - head_importance.min())
+
+ # Print/save matrices
+ np.save(os.path.join(args.output_dir, "attn_entropy.npy"), attn_entropy.detach().cpu().numpy())
+ np.save(os.path.join(args.output_dir, "head_importance.npy"), head_importance.detach().cpu().numpy())
+
+ logger.info("Attention entropies")
+ print_2d_tensor(attn_entropy)
+ logger.info("Head importance scores")
+ print_2d_tensor(head_importance)
+ logger.info("Head ranked by importance scores")
+ head_ranks = torch.zeros(head_importance.numel(), dtype=torch.long, device=args.device)
+ head_ranks[head_importance.view(-1).sort(descending=True)[1]] = torch.arange(
+ head_importance.numel(), device=args.device
+ )
+ head_ranks = head_ranks.view_as(head_importance)
+ print_2d_tensor(head_ranks)
+
+ return attn_entropy, head_importance, preds, labels
+
+
+def mask_heads(args, model, eval_dataloader):
+ """This method shows how to mask head (set some heads to zero), to test the effect on the network,
+ based on the head importance scores, as described in Michel et al. (http://arxiv.org/abs/1905.10650)
+ """
+ _, head_importance, preds, labels = compute_heads_importance(args, model, eval_dataloader, compute_entropy=False)
+ preds = np.argmax(preds, axis=1) if args.output_mode == "classification" else np.squeeze(preds)
+ original_score = glue_compute_metrics(args.task_name, preds, labels)[args.metric_name]
+ logger.info("Pruning: original score: %f, threshold: %f", original_score, original_score * args.masking_threshold)
+
+ new_head_mask = torch.ones_like(head_importance)
+ num_to_mask = max(1, int(new_head_mask.numel() * args.masking_amount))
+
+ current_score = original_score
+ while current_score >= original_score * args.masking_threshold:
+ head_mask = new_head_mask.clone() # save current head mask
+ # heads from least important to most - keep only not-masked heads
+ head_importance[head_mask == 0.0] = float("Inf")
+ current_heads_to_mask = head_importance.view(-1).sort()[1]
+
+ if len(current_heads_to_mask) <= num_to_mask:
+ break
+
+ # mask heads
+ current_heads_to_mask = current_heads_to_mask[:num_to_mask]
+ logger.info("Heads to mask: %s", str(current_heads_to_mask.tolist()))
+ new_head_mask = new_head_mask.view(-1)
+ new_head_mask[current_heads_to_mask] = 0.0
+ new_head_mask = new_head_mask.view_as(head_mask)
+ new_head_mask = new_head_mask.clone().detach()
+ print_2d_tensor(new_head_mask)
+
+ # Compute metric and head importance again
+ _, head_importance, preds, labels = compute_heads_importance(
+ args, model, eval_dataloader, compute_entropy=False, head_mask=new_head_mask
+ )
+ preds = np.argmax(preds, axis=1) if args.output_mode == "classification" else np.squeeze(preds)
+ current_score = glue_compute_metrics(args.task_name, preds, labels)[args.metric_name]
+ logger.info(
+ "Masking: current score: %f, remaining heads %d (%.1f percents)",
+ current_score,
+ new_head_mask.sum(),
+ new_head_mask.sum() / new_head_mask.numel() * 100,
+ )
+
+ logger.info("Final head mask")
+ print_2d_tensor(head_mask)
+ np.save(os.path.join(args.output_dir, "head_mask.npy"), head_mask.detach().cpu().numpy())
+
+ return head_mask
+
+
+def prune_heads(args, model, eval_dataloader, head_mask):
+ """This method shows how to prune head (remove heads weights) based on
+ the head importance scores as described in Michel et al. (http://arxiv.org/abs/1905.10650)
+ """
+ # Try pruning and test time speedup
+ # Pruning is like masking but we actually remove the masked weights
+ before_time = datetime.now()
+ _, _, preds, labels = compute_heads_importance(
+ args, model, eval_dataloader, compute_entropy=False, compute_importance=False, head_mask=head_mask
+ )
+ preds = np.argmax(preds, axis=1) if args.output_mode == "classification" else np.squeeze(preds)
+ score_masking = glue_compute_metrics(args.task_name, preds, labels)[args.metric_name]
+ original_time = datetime.now() - before_time
+
+ original_num_params = sum(p.numel() for p in model.parameters())
+ heads_to_prune = {
+ layer: (1 - head_mask[layer].long()).nonzero().squeeze().tolist() for layer in range(len(head_mask))
+ }
+
+ assert sum(len(h) for h in heads_to_prune.values()) == (1 - head_mask.long()).sum().item()
+ model.prune_heads(heads_to_prune)
+ pruned_num_params = sum(p.numel() for p in model.parameters())
+
+ before_time = datetime.now()
+ _, _, preds, labels = compute_heads_importance(
+ args,
+ model,
+ eval_dataloader,
+ compute_entropy=False,
+ compute_importance=False,
+ head_mask=None,
+ actually_pruned=True,
+ )
+ preds = np.argmax(preds, axis=1) if args.output_mode == "classification" else np.squeeze(preds)
+ score_pruning = glue_compute_metrics(args.task_name, preds, labels)[args.metric_name]
+ new_time = datetime.now() - before_time
+
+ logger.info(
+ "Pruning: original num of params: %.2e, after pruning %.2e (%.1f percents)",
+ original_num_params,
+ pruned_num_params,
+ pruned_num_params / original_num_params * 100,
+ )
+ logger.info("Pruning: score with masking: %f score with pruning: %f", score_masking, score_pruning)
+ logger.info("Pruning: speed ratio (new timing / original timing): %f percents", original_time / new_time * 100)
+
+
+def main():
+ parser = argparse.ArgumentParser()
+ # Required parameters
+ parser.add_argument(
+ "--data_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The input data dir. Should contain the .tsv files (or other data files) for the task.",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ default=None,
+ type=str,
+ required=True,
+ help="Path to pretrained model or model identifier from huggingface.co/models",
+ )
+ parser.add_argument(
+ "--task_name",
+ default=None,
+ type=str,
+ required=True,
+ help="The name of the task to train selected in the list: " + ", ".join(glue_processors.keys()),
+ )
+ parser.add_argument(
+ "--output_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The output directory where the model predictions and checkpoints will be written.",
+ )
+
+ # Other parameters
+ parser.add_argument(
+ "--config_name",
+ default="",
+ type=str,
+ help="Pretrained config name or path if not the same as model_name_or_path",
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ default="",
+ type=str,
+ help="Pretrained tokenizer name or path if not the same as model_name_or_path",
+ )
+ parser.add_argument(
+ "--cache_dir",
+ default=None,
+ type=str,
+ help="Where do you want to store the pre-trained models downloaded from huggingface.co",
+ )
+ parser.add_argument(
+ "--data_subset", type=int, default=-1, help="If > 0: limit the data to a subset of data_subset instances."
+ )
+ parser.add_argument(
+ "--overwrite_output_dir", action="store_true", help="Whether to overwrite data in output directory"
+ )
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+
+ parser.add_argument(
+ "--dont_normalize_importance_by_layer", action="store_true", help="Don't normalize importance score by layers"
+ )
+ parser.add_argument(
+ "--dont_normalize_global_importance",
+ action="store_true",
+ help="Don't normalize all importance scores between 0 and 1",
+ )
+
+ parser.add_argument(
+ "--try_masking", action="store_true", help="Whether to try to mask head until a threshold of accuracy."
+ )
+ parser.add_argument(
+ "--masking_threshold",
+ default=0.9,
+ type=float,
+ help="masking threshold in term of metrics (stop masking when metric < threshold * original metric value).",
+ )
+ parser.add_argument(
+ "--masking_amount", default=0.1, type=float, help="Amount to heads to masking at each masking step."
+ )
+ parser.add_argument("--metric_name", default="acc", type=str, help="Metric to use for head masking.")
+
+ parser.add_argument(
+ "--max_seq_length",
+ default=128,
+ type=int,
+ help=(
+ "The maximum total input sequence length after WordPiece tokenization. \n"
+ "Sequences longer than this will be truncated, sequences shorter padded."
+ ),
+ )
+ parser.add_argument("--batch_size", default=1, type=int, help="Batch size.")
+
+ parser.add_argument("--seed", type=int, default=42)
+ parser.add_argument("--local_rank", type=int, default=-1, help="local_rank for distributed training on gpus")
+ parser.add_argument("--no_cuda", action="store_true", help="Whether not to use CUDA when available")
+ parser.add_argument("--server_ip", type=str, default="", help="Can be used for distant debugging.")
+ parser.add_argument("--server_port", type=str, default="", help="Can be used for distant debugging.")
+ args = parser.parse_args()
+
+ if args.server_ip and args.server_port:
+ # Distant debugging - see https://code.visualstudio.com/docs/python/debugging#_attach-to-a-local-script
+ import ptvsd
+
+ print("Waiting for debugger attach")
+ ptvsd.enable_attach(address=(args.server_ip, args.server_port), redirect_output=True)
+ ptvsd.wait_for_attach()
+
+ # Setup devices and distributed training
+ if args.local_rank == -1 or args.no_cuda:
+ args.device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
+ args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
+ else:
+ torch.cuda.set_device(args.local_rank)
+ args.device = torch.device("cuda", args.local_rank)
+ args.n_gpu = 1
+ torch.distributed.init_process_group(backend="nccl") # Initializes the distributed backend
+
+ # Setup logging
+ logging.basicConfig(level=logging.INFO if args.local_rank in [-1, 0] else logging.WARN)
+ logger.info("device: {} n_gpu: {}, distributed: {}".format(args.device, args.n_gpu, bool(args.local_rank != -1)))
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ if is_main_process(args.local_rank):
+ transformers.utils.logging.set_verbosity_info()
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+
+ # Set seeds
+ set_seed(args.seed)
+
+ # Prepare GLUE task
+ args.task_name = args.task_name.lower()
+ if args.task_name not in glue_processors:
+ raise ValueError("Task not found: %s" % (args.task_name))
+ processor = glue_processors[args.task_name]()
+ args.output_mode = glue_output_modes[args.task_name]
+ label_list = processor.get_labels()
+ num_labels = len(label_list)
+
+ # Load pretrained model and tokenizer
+ #
+ # Distributed training:
+ # The .from_pretrained methods guarantee that only one local process can concurrently
+ # download model & vocab.
+
+ config = AutoConfig.from_pretrained(
+ args.config_name if args.config_name else args.model_name_or_path,
+ num_labels=num_labels,
+ finetuning_task=args.task_name,
+ output_attentions=True,
+ cache_dir=args.cache_dir,
+ )
+ tokenizer = AutoTokenizer.from_pretrained(
+ args.tokenizer_name if args.tokenizer_name else args.model_name_or_path,
+ cache_dir=args.cache_dir,
+ )
+ model = AutoModelForSequenceClassification.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ cache_dir=args.cache_dir,
+ )
+
+ # Distributed and parallel training
+ model.to(args.device)
+ if args.local_rank != -1:
+ model = nn.parallel.DistributedDataParallel(
+ model, device_ids=[args.local_rank], output_device=args.local_rank, find_unused_parameters=True
+ )
+ elif args.n_gpu > 1:
+ model = nn.DataParallel(model)
+
+ # Print/save training arguments
+ os.makedirs(args.output_dir, exist_ok=True)
+ torch.save(args, os.path.join(args.output_dir, "run_args.bin"))
+ logger.info("Training/evaluation parameters %s", args)
+
+ # Prepare dataset for the GLUE task
+ eval_dataset = GlueDataset(args, tokenizer=tokenizer, mode="dev")
+ if args.data_subset > 0:
+ eval_dataset = Subset(eval_dataset, list(range(min(args.data_subset, len(eval_dataset)))))
+ eval_sampler = SequentialSampler(eval_dataset) if args.local_rank == -1 else DistributedSampler(eval_dataset)
+ eval_dataloader = DataLoader(
+ eval_dataset, sampler=eval_sampler, batch_size=args.batch_size, collate_fn=default_data_collator
+ )
+
+ # Compute head entropy and importance score
+ compute_heads_importance(args, model, eval_dataloader)
+
+ # Try head masking (set heads to zero until the score goes under a threshole)
+ # and head pruning (remove masked heads and see the effect on the network)
+ if args.try_masking and args.masking_threshold > 0.0 and args.masking_threshold < 1.0:
+ head_mask = mask_heads(args, model, eval_dataloader)
+ prune_heads(args, model, eval_dataloader, head_mask)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertology/run_prune_gpt.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertology/run_prune_gpt.py
new file mode 100644
index 0000000000000000000000000000000000000000..d227634c2bf787fc7feba327fa2b7ea2312931d7
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/bertology/run_prune_gpt.py
@@ -0,0 +1,391 @@
+#!/usr/bin/env python3
+"""This script is adapted from the Bertology pruning code (https://github.com/huggingface/transformers/blob/783d7d2629e97c5f0c5f9ef01b8c66410275c204/examples/research_projects/bertology/run_bertology.py)
+to prune GPT-like models. The author is @altsoph.
+"""
+
+import argparse
+import logging
+import os
+from datetime import datetime
+
+import numpy as np
+import torch
+from torch import nn
+from torch.utils.data import DataLoader, RandomSampler, TensorDataset
+from tqdm import tqdm
+
+from transformers import GPT2LMHeadModel
+
+
+logger = logging.getLogger(__name__)
+
+
+def save_model(model, dirpath):
+ # save results
+ if os.path.exists(dirpath):
+ if os.path.exists(os.path.join(dirpath, "config.json")) and os.path.isfile(
+ os.path.join(dirpath, "config.json")
+ ):
+ os.remove(os.path.join(dirpath, "config.json"))
+ if os.path.exists(os.path.join(dirpath, "pytorch_model.bin")) and os.path.isfile(
+ os.path.join(dirpath, "pytorch_model.bin")
+ ):
+ os.remove(os.path.join(dirpath, "pytorch_model.bin"))
+ else:
+ os.makedirs(dirpath)
+ model.save_pretrained(dirpath)
+
+
+def entropy(p, unlogit=False):
+ """Compute the entropy of a probability distribution"""
+ exponent = 2
+ if unlogit:
+ p = torch.pow(p, exponent)
+ plogp = p * torch.log(p)
+ plogp[p == 0] = 0
+ return -plogp.sum(dim=-1)
+
+
+def print_2d_tensor(tensor):
+ """Print a 2D tensor"""
+ logger.info("lv, h >\t" + "\t".join(f"{x + 1}" for x in range(len(tensor))))
+ for row in range(len(tensor)):
+ if tensor.dtype != torch.long:
+ logger.info(f"layer {row + 1}:\t" + "\t".join(f"{x:.5f}" for x in tensor[row].cpu().data))
+ else:
+ logger.info(f"layer {row + 1}:\t" + "\t".join(f"{x:d}" for x in tensor[row].cpu().data))
+
+
+def compute_heads_importance(
+ args, model, eval_dataloader, compute_entropy=True, compute_importance=True, head_mask=None, actually_pruned=False
+):
+ """This method shows how to compute:
+ - head attention entropy
+ - head importance scores according to http://arxiv.org/abs/1905.10650
+ """
+ # Prepare our tensors
+ n_layers, n_heads = model.config.num_hidden_layers, model.config.num_attention_heads
+ head_importance = torch.zeros(n_layers, n_heads).to(args.device)
+ attn_entropy = torch.zeros(n_layers, n_heads).to(args.device)
+
+ if head_mask is None:
+ head_mask = torch.ones(n_layers, n_heads).to(args.device)
+
+ head_mask.requires_grad_(requires_grad=True)
+ # If actually pruned attention multi-head, set head mask to None to avoid shape mismatch
+ if actually_pruned:
+ head_mask = None
+
+ tot_tokens = 0.0
+ total_loss = 0.0
+ for step, inputs in enumerate(tqdm(eval_dataloader, desc="Iteration", disable=args.local_rank not in [-1, 0])):
+ inputs = tuple(t.to(args.device) for t in inputs)
+ (input_ids,) = inputs
+
+ # Do a forward pass (not with torch.no_grad() since we need gradients for importance score - see below)
+ outputs = model(input_ids, labels=input_ids, head_mask=head_mask)
+ # (loss), lm_logits, presents, (all hidden_states), (attentions)
+ loss, _, all_attentions = (
+ outputs[0],
+ outputs[1],
+ outputs[-1],
+ ) # Loss and logits are the first, attention the last
+ loss.backward() # Backpropagate to populate the gradients in the head mask
+ total_loss += loss.detach().cpu().numpy()
+ if compute_entropy:
+ for layer, attn in enumerate(all_attentions):
+ masked_entropy = entropy(attn.detach(), True)
+ attn_entropy[layer] += masked_entropy.sum(-1).sum(0).sum(0).detach()
+
+ if compute_importance:
+ head_importance += head_mask.grad.abs().detach()
+ tot_tokens += torch.ones_like(input_ids).float().detach().sum().data
+
+ # Normalize
+ attn_entropy /= tot_tokens
+ head_importance /= tot_tokens
+ # Layerwise importance normalization
+ if not args.dont_normalize_importance_by_layer:
+ exponent = 2
+ norm_by_layer = torch.pow(torch.pow(head_importance, exponent).sum(-1), 1 / exponent)
+ head_importance /= norm_by_layer.unsqueeze(-1) + 1e-20
+
+ if not args.dont_normalize_global_importance:
+ head_importance = (head_importance - head_importance.min()) / (head_importance.max() - head_importance.min())
+
+ # Print matrices
+ if compute_entropy:
+ logger.info("Attention entropies")
+ print_2d_tensor(attn_entropy)
+ if compute_importance:
+ logger.info("Head importance scores")
+ print_2d_tensor(head_importance)
+ logger.info("Head ranked by importance scores")
+ head_ranks = torch.zeros(head_importance.numel(), dtype=torch.long, device=args.device)
+ head_ranks[head_importance.view(-1).sort(descending=True)[1]] = torch.arange(
+ head_importance.numel(), device=args.device
+ )
+ head_ranks = head_ranks.view_as(head_importance)
+ print_2d_tensor(head_ranks)
+ return attn_entropy, head_importance, total_loss
+
+
+def mask_heads(args, model, eval_dataloader):
+ """This method shows how to mask head (set some heads to zero), to test the effect on the network,
+ based on the head importance scores, as described in Michel et al. (http://arxiv.org/abs/1905.10650)
+ """
+ _, head_importance, loss = compute_heads_importance(args, model, eval_dataloader, compute_entropy=False)
+ original_score = 1 / loss # instead of downsteam score use the LM loss
+ logger.info("Pruning: original score: %f, threshold: %f", original_score, original_score * args.masking_threshold)
+
+ new_head_mask = torch.ones_like(head_importance)
+ num_to_mask = max(1, int(new_head_mask.numel() * args.masking_amount))
+
+ current_score = original_score
+ while current_score >= original_score * args.masking_threshold:
+ head_mask = new_head_mask.clone().detach() # save current head mask
+ # heads from least important to most - keep only not-masked heads
+ head_importance[head_mask == 0.0] = float("Inf")
+ current_heads_to_mask = head_importance.view(-1).sort()[1]
+
+ if len(current_heads_to_mask) <= num_to_mask:
+ print("BREAK BY num_to_mask")
+ break
+
+ # mask heads
+ current_heads_to_mask = current_heads_to_mask[:num_to_mask]
+ logger.info("Heads to mask: %s", str(current_heads_to_mask.tolist()))
+ new_head_mask = new_head_mask.view(-1)
+ new_head_mask[current_heads_to_mask] = 0.0
+ new_head_mask = new_head_mask.view_as(head_mask)
+ new_head_mask = new_head_mask.clone().detach()
+ print_2d_tensor(new_head_mask)
+
+ # Compute metric and head importance again
+ _, head_importance, loss = compute_heads_importance(
+ args, model, eval_dataloader, compute_entropy=False, head_mask=new_head_mask
+ )
+ current_score = 1 / loss
+ logger.info(
+ "Masking: current score: %f, remaining heads %d (%.1f percents)",
+ current_score,
+ new_head_mask.sum(),
+ new_head_mask.sum() / new_head_mask.numel() * 100,
+ )
+
+ logger.info("Final head mask")
+ print_2d_tensor(head_mask)
+ np.save(os.path.join(args.output_dir, "head_mask.npy"), head_mask.detach().cpu().numpy())
+
+ return head_mask
+
+
+def prune_heads(args, model, eval_dataloader, head_mask):
+ """This method shows how to prune head (remove heads weights) based on
+ the head importance scores as described in Michel et al. (http://arxiv.org/abs/1905.10650)
+ """
+ # Try pruning and test time speedup
+ # Pruning is like masking but we actually remove the masked weights
+ before_time = datetime.now()
+ _, _, loss = compute_heads_importance(
+ args, model, eval_dataloader, compute_entropy=False, compute_importance=False, head_mask=head_mask
+ )
+ score_masking = 1 / loss
+ original_time = datetime.now() - before_time
+
+ original_num_params = sum(p.numel() for p in model.parameters())
+ heads_to_prune = {
+ layer: (1 - head_mask[layer].long()).nonzero().squeeze().tolist() for layer in range(len(head_mask))
+ }
+
+ for k, v in heads_to_prune.items():
+ if isinstance(v, int):
+ heads_to_prune[k] = [
+ v,
+ ]
+
+ assert sum(len(h) for h in heads_to_prune.values()) == (1 - head_mask.long()).sum().item()
+ model.prune_heads(heads_to_prune)
+ pruned_num_params = sum(p.numel() for p in model.parameters())
+
+ before_time = datetime.now()
+ _, _, loss = compute_heads_importance(
+ args,
+ model,
+ eval_dataloader,
+ compute_entropy=False,
+ compute_importance=False,
+ head_mask=None,
+ actually_pruned=True,
+ )
+
+ score_pruning = 1 / loss
+ new_time = datetime.now() - before_time
+
+ logger.info(
+ "Pruning: original num of params: %.2e, after pruning %.2e (%.1f percents)",
+ original_num_params,
+ pruned_num_params,
+ pruned_num_params / original_num_params * 100,
+ )
+ logger.info("Pruning: score with masking: %f score with pruning: %f", score_masking, score_pruning)
+ logger.info("Pruning: speed ratio (original timing / new timing): %f percents", original_time / new_time * 100)
+ save_model(model, args.output_dir)
+
+
+def main():
+ parser = argparse.ArgumentParser()
+ # Required parameters
+ parser.add_argument(
+ "--data_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The input data dir. Should contain the .tsv files (or other data files) for the task.",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ default=None,
+ type=str,
+ required=True,
+ help="Path to pretrained model or model identifier from huggingface.co/models",
+ )
+ parser.add_argument(
+ "--output_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The output directory where the model predictions and checkpoints will be written.",
+ )
+
+ # Other parameters
+ parser.add_argument(
+ "--config_name",
+ default="",
+ type=str,
+ help="Pretrained config name or path if not the same as model_name_or_path",
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ default="",
+ type=str,
+ help="Pretrained tokenizer name or path if not the same as model_name_or_path",
+ )
+ parser.add_argument(
+ "--cache_dir",
+ default=None,
+ type=str,
+ help="Where do you want to store the pre-trained models downloaded from s3",
+ )
+ parser.add_argument(
+ "--data_subset", type=int, default=-1, help="If > 0: limit the data to a subset of data_subset instances."
+ )
+ parser.add_argument(
+ "--overwrite_output_dir", action="store_true", help="Whether to overwrite data in output directory"
+ )
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+
+ parser.add_argument(
+ "--dont_normalize_importance_by_layer", action="store_true", help="Don't normalize importance score by layers"
+ )
+ parser.add_argument(
+ "--dont_normalize_global_importance",
+ action="store_true",
+ help="Don't normalize all importance scores between 0 and 1",
+ )
+
+ parser.add_argument(
+ "--try_masking", action="store_true", help="Whether to try to mask head until a threshold of accuracy."
+ )
+ parser.add_argument(
+ "--masking_threshold",
+ default=0.9,
+ type=float,
+ help="masking threshold in term of metrics (stop masking when metric < threshold * original metric value).",
+ )
+ parser.add_argument(
+ "--masking_amount", default=0.1, type=float, help="Amount to heads to masking at each masking step."
+ )
+ parser.add_argument("--metric_name", default="acc", type=str, help="Metric to use for head masking.")
+
+ parser.add_argument(
+ "--max_seq_length",
+ default=128,
+ type=int,
+ help=(
+ "The maximum total input sequence length after WordPiece tokenization. \n"
+ "Sequences longer than this will be truncated, sequences shorter padded."
+ ),
+ )
+ parser.add_argument("--batch_size", default=1, type=int, help="Batch size.")
+
+ parser.add_argument("--seed", type=int, default=42)
+ parser.add_argument("--local_rank", type=int, default=-1, help="local_rank for distributed training on gpus")
+ parser.add_argument("--no_cuda", action="store_true", help="Whether not to use CUDA when available")
+ parser.add_argument("--server_ip", type=str, default="", help="Can be used for distant debugging.")
+ parser.add_argument("--server_port", type=str, default="", help="Can be used for distant debugging.")
+ args = parser.parse_args()
+
+ if args.server_ip and args.server_port:
+ # Distant debugging - see https://code.visualstudio.com/docs/python/debugging#_attach-to-a-local-script
+ import ptvsd
+
+ print("Waiting for debugger attach")
+ ptvsd.enable_attach(address=(args.server_ip, args.server_port), redirect_output=True)
+ ptvsd.wait_for_attach()
+
+ # Setup devices and distributed training
+ if args.local_rank == -1 or args.no_cuda:
+ args.device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
+ args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
+ else:
+ torch.cuda.set_device(args.local_rank)
+ args.device = torch.device("cuda", args.local_rank)
+ args.n_gpu = 1
+ torch.distributed.init_process_group(backend="nccl") # Initializes the distributed backend
+
+ # Setup logging
+ logging.basicConfig(level=logging.INFO if args.local_rank in [-1, 0] else logging.WARN)
+ logger.info("device: {} n_gpu: {}, distributed: {}".format(args.device, args.n_gpu, bool(args.local_rank != -1)))
+
+ model = GPT2LMHeadModel.from_pretrained(args.model_name_or_path)
+
+ # Distributed and parallel training
+ model.to(args.device)
+ if args.local_rank != -1:
+ model = nn.parallel.DistributedDataParallel(
+ model, device_ids=[args.local_rank], output_device=args.local_rank, find_unused_parameters=True
+ )
+ elif args.n_gpu > 1:
+ model = nn.DataParallel(model)
+
+ # Print/save training arguments
+ os.makedirs(args.output_dir, exist_ok=True)
+ torch.save(args, os.path.join(args.output_dir, "run_args.bin"))
+ logger.info("Training/evaluation parameters %s", args)
+
+ # Prepare dataset
+ numpy_data = np.concatenate(
+ [
+ np.loadtxt(args.data_dir, dtype=np.int64),
+ ]
+ )
+ train_tensor_dataset = (torch.from_numpy(numpy_data),)
+ train_data = TensorDataset(*train_tensor_dataset)
+ train_sampler = RandomSampler(train_data)
+ eval_dataloader = DataLoader(train_data, sampler=train_sampler, batch_size=args.batch_size)
+
+ # Compute head entropy and importance score
+ compute_heads_importance(args, model, eval_dataloader)
+
+ # Try head masking (set heads to zero until the score goes under a threshole)
+ # and head pruning (remove masked heads and see the effect on the network)
+ if args.try_masking and args.masking_threshold > 0.0 and args.masking_threshold < 1.0:
+ head_mask = mask_heads(args, model, eval_dataloader)
+ prune_heads(args, model, eval_dataloader, head_mask)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..f0af3d144f781af190e3bad0f6067b8232023d34
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/README.md
@@ -0,0 +1,316 @@
+# CodeParrot 🦜
+
+
+
+## What is this about?
+This is an open-source effort to train and evaluate code generation models. CodeParrot 🦜 is a GPT-2 model trained from scratch on Python code. The highlights of this project are:
+- initialize and train a GPT-2 language model from scratch for code generation
+- train a custom tokenizer adapted for Python code
+- clean and deduplicate a large (>100GB) dataset with `datasets`
+- train with `accelerate` on multiple GPUs using data parallelism and mixed precision
+- continuously push checkpoints to the hub with `huggingface_hub`
+- stream the dataset with `datasets` during training to avoid disk bottlenecks
+- apply the `code_eval` metric in `datasets` to evaluate on [OpenAI's _HumanEval_ benchmark](https://huggingface.co/datasets/openai_humaneval)
+- showcase examples for downstream tasks with code models in [examples](https://github.com/huggingface/transformers/tree/main/examples/research_projects/codeparrot/examples) folder:
+ - Algorithmic complexity prediction
+ - Code generation from english text
+ - Code explanation
+
+## Installation
+To install the dependencies simply run the following command:
+```bash
+pip install -r requirements.txt
+```
+
+To reproduce the results you can follow the scripts in the following sections. Note that we don't always show all possible arguments to the scripts. To get the full list of arguments with descriptions you can run the following command on any script:
+
+```bash
+python scripts/some_script.py --help
+```
+
+Before you run any of the scripts make sure you are logged in and can push to the hub:
+
+```bash
+huggingface-cli login
+```
+
+Additionally, sure you have git-lfs installed. You can find instructions for how to install it [here](https://git-lfs.github.com/).
+
+## Dataset
+The source of the dataset is the GitHub dump available on Google's [BigQuery](https://cloud.google.com/blog/topics/public-datasets/github-on-bigquery-analyze-all-the-open-source-code). The database was queried for all Python files with less than 1MB in size resulting in a 180GB dataset with over 20M files. The dataset is available on the Hugging Face Hub [here](https://huggingface.co/datasets/transformersbook/codeparrot).
+
+### Preprocessing
+The raw dataset contains many duplicates. We deduplicated and filtered the dataset using the heuristics proposed in OpenAI's Codex [paper](https://arxiv.org/abs/2107.03374) and some new ones:
+
+- exact deduplication using each file's hash after having removed whistespaces.
+- near deduplication using MinHash and Jaccard similarity. MinHash with a Jaccard threshold (default=0.85) is first used to create duplicate clusters. Then these clusters are then reduced to unique files based on the exact Jaccard similarity. See `deduplicate_dataset` in `minhash_deduplication.py` for a detailed description.
+- filtering files with max line length > 1000
+- filtering files with mean line length > 100
+- fraction of alphanumeric characters < 0.25
+- containing the word "auto-generated" or similar in the first 5 lines
+- filtering with a probability of 0.7 of files with a mention of "test file" or "configuration file" or similar in the first 5 lines
+- filtering with a probability of 0.7 of files with high occurrence of the keywords "test " or "config"
+- filtering with a probability of 0.7 of files without a mention of the keywords `def` , `for`, `while` and `class`
+- filtering files that use the assignment operator `=` less than 5 times
+- filtering files with ratio between number of characters and number of tokens after tokenization < 1.5 (the average ratio is 3.6)
+
+The script to process the full dataset can be found in `scripts/preprocessing.py`. Executing the script on 16 vCPUs takes roughly 3h and removes 70% of the original dataset. The cleaned [train](https://huggingface.co/datasets/codeparrot/codeparrot-clean-train-v2) and [validation](https://huggingface.co/datasets/codeparrot/codeparrot-clean-valid-v2) splits are also available on the Hub if you want to skip this step or use the data for another project.
+
+To execute the preprocessing run the following command:
+```bash
+python scripts/preprocessing.py \
+--dataset_name transformersbook/codeparrot \
+--output_dir codeparrot-clean
+```
+During preprocessing the dataset is downloaded and stored locally as well as caches of the computations. Make sure you have more than 500GB free disk space to execute it.
+
+### Pretokenization
+The tokenization of the data might be slow during the training especially for small models. We provide code to pretokenize the data beforehand in `scripts/pretokenizing.py`, but this step is optional. The dataset is downloaded and stored locally and the tokenized data is pushed to the hub. The tokenized clean [train](https://huggingface.co/datasets/codeparrot/tokenized-codeparrot-train) and [validation](https://huggingface.co/datasets/codeparrot/tokenized-codeparrot-valid) datasets are available if you want to use them directly.
+
+To execute the pretokenization, for the clean train data for instance, run the following command:
+```bash
+python scripts/pretokenizing.py \
+--dataset_name codeparrot/codeparrot-clean-train \
+--tokenized_data_repo tokenized-codeparrot-train
+```
+
+## Tokenizer
+Before training a new model for code we create a new tokenizer that is efficient at code tokenization. To train the tokenizer you can run the following command:
+```bash
+python scripts/bpe_training.py \
+ --base_tokenizer openai-community/gpt2 \
+ --dataset_name codeparrot/codeparrot-clean-train
+```
+
+_Note:_ We originally trained the tokenizer on the unprocessed train split of the dataset `transformersbook/codeparrot-train`.
+
+## Training
+The models are randomly initialized and trained from scratch. To initialize a new model you can run:
+
+```bash
+python scripts/initialize_model.py \
+--config_name openai-community/gpt2-large \
+--tokenizer_name codeparrot/codeparrot \
+--model_name codeparrot \
+--push_to_hub True
+```
+This will initialize a new model with the architecture and configuration of `openai-community/gpt2-large` and use the tokenizer to appropriately size the input embeddings. Finally, the initilaized model is pushed the hub.
+
+We can either pass the name of a text dataset or a pretokenized dataset which speeds up training a bit.
+Now that the tokenizer and model are also ready we can start training the model. The main training script is built with `accelerate` to scale across a wide range of platforms and infrastructure scales. We train two models with [110M](https://huggingface.co/codeparrot/codeparrot-small/) and [1.5B](https://huggingface.co/codeparrot/codeparrot/) parameters for 25-30B tokens on a 16xA100 (40GB) machine which takes 1 day and 1 week, respectively.
+
+First you need to configure `accelerate` and login to Weights & Biases:
+
+```bash
+accelerate config
+wandb login
+```
+
+Note that during the `accelerate` configuration we enabled FP16. Then to train the large model you can run
+
+```bash
+accelerate launch scripts/codeparrot_training.py
+```
+
+If you want to train the small model you need to make some modifications:
+
+```bash
+accelerate launch scripts/codeparrot_training.py \
+--model_ckpt codeparrot/codeparrot-small \
+--train_batch_size 12 \
+--valid_batch_size 12 \
+--learning_rate 5e-4 \
+--num_warmup_steps 2000 \
+--gradient_accumulation 1 \
+--gradient_checkpointing False \
+--max_train_steps 150000 \
+--save_checkpoint_steps 15000
+```
+
+Recall that you can see the full set of possible options with descriptions (for all scripts) by running:
+
+```bash
+python scripts/codeparrot_training.py --help
+```
+
+Instead of streaming the dataset from the hub you can also stream it from disk. This can be helpful for long training runs where the connection can be interrupted sometimes. To stream locally you simply need to clone the datasets and replace the dataset name with their path. In this example we store the data in a folder called `data`:
+
+```bash
+git lfs install
+mkdir data
+git -C "./data" clone https://huggingface.co/datasets/codeparrot/codeparrot-clean-train
+git -C "./data" clone https://huggingface.co/datasets/codeparrot/codeparrot-clean-valid
+```
+
+And then pass the paths to the datasets when we run the training script:
+
+```bash
+accelerate launch scripts/codeparrot_training.py \
+--model_ckpt codeparrot/codeparrot-small \
+--dataset_name_train ./data/codeparrot-clean-train \
+--dataset_name_valid ./data/codeparrot-clean-valid \
+--train_batch_size 12 \
+--valid_batch_size 12 \
+--learning_rate 5e-4 \
+--num_warmup_steps 2000 \
+--gradient_accumulation 1 \
+--gradient_checkpointing False \
+--max_train_steps 150000 \
+--save_checkpoint_steps 15000
+```
+
+## Evaluation
+For evaluating the language modeling loss on the validation set or any other dataset you can use the following command:
+```bash
+python scripts/validation_loss.py \
+--model_ckpt codeparrot/codeparrot \
+--dataset_name codeparrot/codeparrot-clean-valid
+```
+In addition we evaluate the model on OpenAI's _HumanEval_ benchmark. You can run the evaluation with the following command:
+
+```bash
+accelerate launch scripts/human_eval.py --model_ckpt codeparrot/codeparrot \
+--do_sample True \
+--temperature 0.2 \
+--top_p 0.95 \
+--n_samples=200 \
+--HF_ALLOW_CODE_EVAL="0"
+```
+
+The results as well as reference values are shown in the following table:
+
+| Model | pass@1 | pass@10 | pass@100|
+|-------|--------|---------|---------|
+|CodeParrot 🦜 (110M) | 3.80% | 6.57% | 12.78% |
+|CodeParrot 🦜 (1.5B) | 3.99% | 8.69% | 17.88% |
+|||||
+|Codex (25M)| 3.21% | 7.1% | 12.89%|
+|Codex (85M)| 8.22% | 12.81% | 22.40% |
+|Codex (300M)| 13.17%| 20.37% | 36.27% |
+|Codex (12B)| 28.81%| 46.81% | 72.31% |
+|||||
+|GPT-neo (125M)| 0.75% | 1.88% | 2.97% |
+|GPT-neo (1.5B)| 4.79% | 7.47% | 16.30% |
+|GPT-neo (2.7B)| 6.41% | 11.27% | 21.37% |
+|GPT-J (6B)| 11.62% | 15.74% | 27.74% |
+
+The numbers were obtained by sampling with `T = [0.2, 0.6, 0.8]` and picking the best value for each metric. Both CodeParrot 🦜 models are still underfitted and longer training would likely improve the performance.
+
+## Demo
+Give the model a shot yourself! There are three demos to interact with CodeParrot 🦜:
+- [Code generation](https://huggingface.co/spaces/codeparrot/codeparrot-generation)
+- [Code highlighting](https://huggingface.co/spaces/codeparrot/codeparrot-highlighting)
+- [Comparison to other code models](https://huggingface.co/spaces/codeparrot/loubnabnl/code-generation-models)
+
+## Training with Megatron
+[Megatron](https://github.com/NVIDIA/Megatron-LM) is a framework developed by NVIDIA for training large transformer models. While the CodeParrot code is easy to follow and modify to your needs the Megatron framework lets you train models faster. Below we explain how to use it.
+
+### Setup
+You can pull an NVIDIA PyTorch Container that comes with all the required installations from [NGC](https://catalog.ngc.nvidia.com/orgs/nvidia/containers/pytorch). See [documentation](https://docs.nvidia.com/deeplearning/frameworks/pytorch-release-notes/index.html) for more details:
+
+With the following Docker command you can run the container (`xx.xx` denotes your Docker version), and clone [Megatron repository](https://github.com/NVIDIA/Megatron-LM) into it:
+```bash
+docker run --gpus all -it --rm nvcr.io/nvidia/pytorch:xx.xx-py3
+git clone https://github.com/NVIDIA/Megatron-LM
+```
+
+You also need to add the vocabulary file and merges table of the tokenizer that you trained on code into the container. You can also find these files in [vocab.json](https://huggingface.co/codeparrot/codeparrot/raw/main/vocab.json) and [merges.txt](https://huggingface.co/codeparrot/codeparrot/raw/main/merges.txt).
+```bash
+sudo docker cp vocab.json CONTAINER_ID:/workspace/Megatron-LM
+sudo docker cp merges.txt CONTAINER_ID:/workspace/Megatron-LM
+```
+
+### Data preprocessing
+The training data requires preprocessing. First, you need to convert it into a loose json format, with one json containing a text sample per line. In python this can be done this way:
+```python
+from datasets import load_dataset
+
+train_data = load_dataset('codeparrot/codeparrot-clean-train', split='train')
+train_data.to_json("codeparrot_data.json", lines=True)
+```
+
+The data is then tokenized, shuffled and processed into a binary format for training using the following command:
+```bash
+pip install nltk
+cd Megatron-LM
+python tools/preprocess_data.py \
+ --input codeparrot_data.json \
+ --output-prefix codeparrot \
+ --vocab vocab.json \
+ --dataset-impl mmap \
+ --tokenizer-type GPT2BPETokenizer \
+ --merge-file merges.txt \
+ --json-keys content \
+ --workers 32 \
+ --chunk-size 25 \
+ --append-eod
+```
+This outputs two files `codeparrot_content_document.idx` and `codeparrot_content_document.bin` which are used in the training.
+
+### Training
+You can configure the model architecture and training parameters as shown below, or put it in a bash script that you will run. This runs on 8 GPUs the 110M parameter CodeParrot pretraining, with the same settings as before. Note that the data is partitioned by default into a 969:30:1 ratio for training/validation/test sets.
+```bash
+GPUS_PER_NODE=8
+MASTER_ADDR=localhost
+MASTER_PORT=6001
+NNODES=1
+NODE_RANK=0
+WORLD_SIZE=$(($GPUS_PER_NODE*$NNODES))
+DISTRIBUTED_ARGS="--nproc_per_node $GPUS_PER_NODE --nnodes $NNODES --node_rank $NODE_RANK --master_addr $MASTER_ADDR --master_port $MASTER_PORT"
+CHECKPOINT_PATH=/workspace/Megatron-LM/experiments/codeparrot-small
+VOCAB_FILE=vocab.json
+MERGE_FILE=merges.txt
+DATA_PATH=codeparrot_content_document
+GPT_ARGS="--num-layers 12
+--hidden-size 768
+--num-attention-heads 12
+--seq-length 1024
+--max-position-embeddings 1024
+--micro-batch-size 12
+--global-batch-size 192
+--lr 0.0005
+--train-iters 150000
+--lr-decay-iters 150000
+--lr-decay-style cosine
+--lr-warmup-iters 2000
+--weight-decay .1
+--adam-beta2 .999
+--fp16
+--log-interval 10
+--save-interval 2000
+--eval-interval 200
+--eval-iters 10
+"
+TENSORBOARD_ARGS="--tensorboard-dir experiments/tensorboard"
+python3 -m torch.distributed.launch $DISTRIBUTED_ARGS \
+ pretrain_gpt.py \
+ --tensor-model-parallel-size 1 \
+ --pipeline-model-parallel-size 1 \
+ $GPT_ARGS \
+ --vocab-file $VOCAB_FILE \
+ --merge-file $MERGE_FILE \
+ --save $CHECKPOINT_PATH \
+ --load $CHECKPOINT_PATH \
+ --data-path $DATA_PATH \
+ $TENSORBOARD_ARGS
+```
+The training takes almost 12 hours in this setting.
+
+### Convert model to `transformers`
+After training we want to use the model in `transformers` e.g. to evaluate it on HumanEval. You can convert it to `transformers` following [this](https://huggingface.co/nvidia/megatron-gpt2-345m) tutorial. For instance, after the training is finished you can copy the weights of the last iteration 150k and convert the `model_optim_rng.pt` file to a `pytorch_model.bin` file that is supported by `transformers`.
+
+```bash
+mkdir -p nvidia/megatron-codeparrot-small
+sudo docker cp CONTAINER_ID:/workspace/Megatron-LM/experiments/codeparrot-small/iter_0150000/mp_rank_00/model_optim_rng.pt nvidia/megatron-codeparrot-small
+git clone https://github.com/huggingface/transformers.git
+git clone https://github.com/NVIDIA/Megatron-LM.git
+export PYTHONPATH=Megatron-LM
+python transformers/src/transformers/models/megatron_gpt2/convert_megatron_gpt2_checkpoint.py nvidia/megatron-codeparrot-small/model_optim_rng.pt
+```
+Be careful, you will need to replace the generated vocabulary file and merges table after the conversion, with the original ones if you plan to load the tokenizer from there.
+
+## Further Resources
+A detailed description of the project can be found in the chapter "Training Transformers from Scratch" in the upcoming O'Reilly book [Natural Language Processing with Transformers](https://learning.oreilly.com/library/view/natural-language-processing/9781098103231/).
+
+This example was provided by [Leandro von Werra](www.github.com/lvwerra).
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/examples/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/examples/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..c1980262d8275b9e0a9abe3d5a00d3c955ddb73d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/examples/README.md
@@ -0,0 +1,58 @@
+# Examples
+In this folder we showcase some examples to use code models for downstream tasks.
+
+## Complexity prediction
+In this task we want to predict the complexity of Java programs in [CodeComplex](https://huggingface.co/datasets/codeparrot/codecomplex) dataset. Using Hugging Face `trainer`, we finetuned [multilingual CodeParrot](https://huggingface.co/codeparrot/codeparrot-small-multi) and [UniXcoder](https://huggingface.co/microsoft/unixcoder-base-nine) on it, and we used the latter to build this Java complexity prediction [space](https://huggingface.co/spaces/codeparrot/code-complexity-predictor) on Hugging Face hub.
+
+To fine-tune a model on this dataset you can use the following commands:
+
+```python
+python train_complexity_predictor.py \
+ --model_ckpt microsoft/unixcoder-base-nine \
+ --num_epochs 60 \
+ --num_warmup_steps 10 \
+ --batch_size 8 \
+ --learning_rate 5e-4
+```
+
+## Code generation: text to python
+In this task we want to train a model to generate code from english text. We finetuned Codeparrot-small on [github-jupyter-text-to-code](https://huggingface.co/datasets/codeparrot/github-jupyter-text-to-code), a dataset where the samples are a succession of docstrings and their Python code, originally extracted from Jupyter notebooks parsed in this [dataset](https://huggingface.co/datasets/codeparrot/github-jupyter-parsed).
+
+To fine-tune a model on this dataset we use the same [script](https://github.com/huggingface/transformers/blob/main/examples/research_projects/codeparrot/scripts/codeparrot_training.py) as the pretraining of codeparrot:
+
+```python
+accelerate launch scripts/codeparrot_training.py \
+ --model_ckpt codeparrot/codeparrot-small \
+ --dataset_name_train codeparrot/github-jupyter-text-to-code \
+ --dataset_name_valid codeparrot/github-jupyter-text-to-code \
+ --train_batch_size 12 \
+ --valid_batch_size 12 \
+ --learning_rate 5e-4 \
+ --num_warmup_steps 100 \
+ --gradient_accumulation 1 \
+ --gradient_checkpointing False \
+ --max_train_steps 3000 \
+ --save_checkpoint_steps 200 \
+ --save_dir jupyter-text-to-python
+```
+
+## Code explanation: python to text
+In this task we want to train a model to explain python code. We finetuned Codeparrot-small on [github-jupyter-code-to-text](https://huggingface.co/datasets/codeparrot/github-jupyter-code-to-text), a dataset where the samples are a succession of Python code and its explanation as a docstring, we just inverted the order of text and code pairs in github-jupyter-code-to-text dataset and added the delimiters "Explanation:" and "End of explanation" inside the doctrings.
+
+To fine-tune a model on this dataset we use the same [script](https://github.com/huggingface/transformers/blob/main/examples/research_projects/codeparrot/scripts/codeparrot_training.py) as the pretraining of codeparrot:
+
+```python
+accelerate launch scripts/codeparrot_training.py \
+ --model_ckpt codeparrot/codeparrot-small \
+ --dataset_name_train codeparrot/github-jupyter-code-to-text \
+ --dataset_name_valid codeparrot/github-jupyter-code-to-text \
+ --train_batch_size 12 \
+ --valid_batch_size 12 \
+ --learning_rate 5e-4 \
+ --num_warmup_steps 100 \
+ --gradient_accumulation 1 \
+ --gradient_checkpointing False \
+ --max_train_steps 3000 \
+ --save_checkpoint_steps 200 \
+ --save_dir jupyter-python-to-text
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/examples/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/examples/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..64ee5b508f77a9c2fb6fd533204ed9823c5e13eb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/examples/requirements.txt
@@ -0,0 +1,5 @@
+datasets==2.3.2
+transformers==4.38.0
+wandb==0.13.1
+evaluate==0.2.2
+scikit-learn==1.5.0
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/examples/train_complexity_predictor.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/examples/train_complexity_predictor.py
new file mode 100644
index 0000000000000000000000000000000000000000..de06b988db634c0112e15dd2baf0d689d3ad2256
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/examples/train_complexity_predictor.py
@@ -0,0 +1,132 @@
+import argparse
+from copy import deepcopy
+
+import numpy as np
+from datasets import ClassLabel, DatasetDict, load_dataset
+from evaluate import load
+
+from transformers import (
+ AutoModelForSequenceClassification,
+ AutoTokenizer,
+ DataCollatorWithPadding,
+ Trainer,
+ TrainerCallback,
+ TrainingArguments,
+ set_seed,
+)
+
+
+def get_args():
+ parser = argparse.ArgumentParser()
+ parser.add_argument("--model_ckpt", type=str, default="microsoft/unixcoder-base-nine")
+ parser.add_argument("--num_epochs", type=int, default=5)
+ parser.add_argument("--batch_size", type=int, default=6)
+ parser.add_argument("--gradient_accumulation_steps", type=int, default=1)
+ parser.add_argument("--freeze", type=bool, default=True)
+ parser.add_argument("--learning_rate", type=float, default=5e-4)
+ parser.add_argument("--seed", type=int, default=0)
+ parser.add_argument("--lr_scheduler_type", type=str, default="cosine")
+ parser.add_argument("--num_warmup_steps", type=int, default=10)
+ parser.add_argument("--weight_decay", type=float, default=0.01)
+ parser.add_argument("--output_dir", type=str, default="./results")
+ return parser.parse_args()
+
+
+metric = load("accuracy")
+
+
+def compute_metrics(eval_pred):
+ predictions, labels = eval_pred
+ predictions = np.argmax(predictions, axis=1)
+ return metric.compute(predictions=predictions, references=labels)
+
+
+class CustomCallback(TrainerCallback):
+ def __init__(self, trainer) -> None:
+ super().__init__()
+ self._trainer = trainer
+
+ def on_epoch_end(self, args, state, control, **kwargs):
+ if control.should_evaluate:
+ control_copy = deepcopy(control)
+ self._trainer.evaluate(eval_dataset=self._trainer.train_dataset, metric_key_prefix="train")
+ return control_copy
+
+
+def main():
+ args = get_args()
+ set_seed(args.seed)
+
+ dataset = load_dataset("codeparrot/codecomplex", split="train")
+ train_test = dataset.train_test_split(test_size=0.2)
+ test_validation = train_test["test"].train_test_split(test_size=0.5)
+ train_test_validation = DatasetDict(
+ {
+ "train": train_test["train"],
+ "test": test_validation["train"],
+ "valid": test_validation["test"],
+ }
+ )
+
+ print("Loading tokenizer and model")
+ tokenizer = AutoTokenizer.from_pretrained(args.model_ckpt)
+ tokenizer.pad_token = tokenizer.eos_token
+ model = AutoModelForSequenceClassification.from_pretrained(args.model_ckpt, num_labels=7)
+ model.config.pad_token_id = model.config.eos_token_id
+
+ if args.freeze:
+ for param in model.roberta.parameters():
+ param.requires_grad = False
+
+ labels = ClassLabel(num_classes=7, names=list(set(train_test_validation["train"]["complexity"])))
+
+ def tokenize(example):
+ inputs = tokenizer(example["src"], truncation=True, max_length=1024)
+ label = labels.str2int(example["complexity"])
+ return {
+ "input_ids": inputs["input_ids"],
+ "attention_mask": inputs["attention_mask"],
+ "label": label,
+ }
+
+ tokenized_datasets = train_test_validation.map(
+ tokenize,
+ batched=True,
+ remove_columns=train_test_validation["train"].column_names,
+ )
+ data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
+
+ training_args = TrainingArguments(
+ output_dir=args.output_dir,
+ learning_rate=args.learning_rate,
+ lr_scheduler_type=args.lr_scheduler_type,
+ eval_strategy="epoch",
+ save_strategy="epoch",
+ logging_strategy="epoch",
+ per_device_train_batch_size=args.batch_size,
+ per_device_eval_batch_size=args.batch_size,
+ num_train_epochs=args.num_epochs,
+ gradient_accumulation_steps=args.gradient_accumulation_steps,
+ weight_decay=0.01,
+ metric_for_best_model="accuracy",
+ run_name="complexity-java",
+ report_to="wandb",
+ )
+
+ trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=tokenized_datasets["train"],
+ eval_dataset=tokenized_datasets["valid"],
+ tokenizer=tokenizer,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics,
+ )
+
+ print("Training...")
+ trainer.add_callback(CustomCallback(trainer))
+ trainer.train()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..ee4fc0691b06a69a411a741c4004b2555be30f99
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/requirements.txt
@@ -0,0 +1,9 @@
+transformers==4.38.0
+datasets==1.16.0
+wandb==0.12.0
+tensorboard==2.6.0
+torch==2.2.0
+huggingface-hub==0.1.0
+git+https://github.com/huggingface/accelerate.git@3c45b6f760ad8745be9ebc9bbb26f5b04dea4abe
+datasketch==1.5.7
+dpu_utils
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/arguments.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/arguments.py
new file mode 100644
index 0000000000000000000000000000000000000000..1540319b3daf65726400baf7681fb73afe41aaff
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/arguments.py
@@ -0,0 +1,220 @@
+from dataclasses import dataclass, field
+from typing import Optional
+
+
+@dataclass
+class TrainingArguments:
+ """
+ Configuration for training model.
+ """
+
+ model_ckpt: Optional[str] = field(
+ default="codeparrot/codeparrot", metadata={"help": "Model name or path of model to be trained."}
+ )
+ save_dir: Optional[str] = field(
+ default="./", metadata={"help": "Save dir where model repo is cloned and models updates are saved to."}
+ )
+ dataset_name_train: Optional[str] = field(
+ default="codeparrot/codeparrot-clean-train", metadata={"help": "Name or path of training dataset."}
+ )
+ dataset_name_valid: Optional[str] = field(
+ default="codeparrot/codeparrot-clean-valid", metadata={"help": "Name or path of validation dataset."}
+ )
+ train_batch_size: Optional[int] = field(default=2, metadata={"help": "Batch size for training."})
+ valid_batch_size: Optional[int] = field(default=2, metadata={"help": "Batch size for evaluation."})
+ weight_decay: Optional[float] = field(default=0.1, metadata={"help": "Value of weight decay."})
+ shuffle_buffer: Optional[int] = field(
+ default=10000, metadata={"help": "Size of buffer used to shuffle streaming dataset."}
+ )
+ learning_rate: Optional[float] = field(default=2e-4, metadata={"help": "Learning rate fo training."})
+ lr_scheduler_type: Optional[str] = field(default="cosine", metadata={"help": "Learning rate."})
+ num_warmup_steps: Optional[int] = field(
+ default=750, metadata={"help": "Number of warmup steps in the learning rate schedule."}
+ )
+ gradient_accumulation_steps: Optional[int] = field(
+ default=16, metadata={"help": "Number of gradient accumulation steps."}
+ )
+ gradient_checkpointing: Optional[bool] = field(
+ default=True, metadata={"help": "Use gradient checkpointing to reduce memory footprint."}
+ )
+ max_train_steps: Optional[int] = field(default=50000, metadata={"help": "Maximum number of training steps."})
+ max_eval_steps: Optional[int] = field(
+ default=-1, metadata={"help": "Maximum number of evaluation steps. If -1 the full dataset is evaluated."}
+ )
+ seq_length: Optional[int] = field(default=1024, metadata={"help": "Sequence lengths used for training."})
+ seed: Optional[int] = field(default=1, metadata={"help": "Training seed."})
+ save_checkpoint_steps: Optional[int] = field(
+ default=1024,
+ metadata={"help": "Interval to save checkpoints. Measured as number of forward passes not training steps."},
+ )
+ resume_from_checkpoint: Optional[str] = field(
+ default=None, metadata={"help": "States path if the training should continue from a checkpoint folder."}
+ )
+ tokenized: Optional[bool] = field(default=False, metadata={"help": "If True the data is pretokenized."})
+
+
+@dataclass
+class EvaluationArguments:
+ """
+ Configuration for evaluating model.
+ """
+
+ model_ckpt: Optional[str] = field(
+ default="codeparrot/codeparrot", metadata={"help": "Model name or path of model to be evaluated."}
+ )
+ dataset_name: Optional[str] = field(
+ default="codeparrot/codeparrot-clean-valid", metadata={"help": "Name or path of validation dataset."}
+ )
+ batch_size: Optional[int] = field(default=2, metadata={"help": "Batch size used for evaluation."})
+ max_eval_steps: Optional[int] = field(
+ default=-1, metadata={"help": "Maximum number of evaluation steps. If -1 the full dataset is evaluated."}
+ )
+ seq_length: Optional[int] = field(default=1024, metadata={"help": "Length of sequences to be evaluated."})
+ seed: Optional[int] = field(default=1, metadata={"help": "Random seed used for evaluation."})
+
+
+@dataclass
+class HumanEvalArguments:
+ """
+ Configuration for running evaluation on HumanEval dataset.
+ """
+
+ model_ckpt: Optional[str] = field(
+ default="codeparrot/codeparrot", metadata={"help": "Model name or path of model to be evaluated."}
+ )
+ num_workers: Optional[int] = field(default=None, metadata={"help": "Number of workers used for code evaluation."})
+ num_tasks: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of human-eval tasks to run. If not included all tasks are evaluated."},
+ )
+ do_sample: Optional[bool] = field(
+ default=True, metadata={"help": "Sample from the language model's output distribution."}
+ )
+ temperature: Optional[float] = field(default=0.2, metadata={"help": "Sampling temperature used for generation."})
+ max_new_tokens: Optional[int] = field(default=256, metadata={"help": "Maximum number of newly generated tokens."})
+ top_k: Optional[int] = field(default=0, metadata={"help": "Top-k parameter used for generation."})
+ top_p: Optional[float] = field(default=0.95, metadata={"help": "Top-p parameter used for nucleus sampling."})
+ batch_size: Optional[int] = field(default=10, metadata={"help": "Number of generations to run in parallel."})
+ n_samples: Optional[int] = field(
+ default=200, metadata={"help": "Number of completions to generate for each sample."}
+ )
+ seed: Optional[int] = field(default=1, metadata={"help": "Random seed used for evaluation."})
+ output_file: Optional[str] = field(
+ default="eval_results.json", metadata={"help": "Random seed used for evaluation."}
+ )
+ HF_ALLOW_CODE_EVAL: Optional[str] = field(
+ default="0", metadata={"help": "Allow `code_eval` to execute Python code on machine"}
+ )
+ device_int: Optional[int] = field(
+ default=-1,
+ metadata={
+ "help": (
+ "Determine which device to run the `text-generation` Pipeline on. -1 is CPU and any zero or positive"
+ " number corresponds to which GPU device id to run on."
+ )
+ },
+ )
+
+
+@dataclass
+class PreprocessingArguments:
+ """
+ Configuration for preprocessing data.
+ """
+
+ num_workers: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": "The number of CPU cores to use for parallel preprocessing. Default uses the maximum available."
+ },
+ )
+ dataset_name: Optional[str] = field(
+ default="transformersbook/codeparrot", metadata={"help": "Folder or name of dataset to process."}
+ )
+ output_dir: Optional[str] = field(
+ default="codeparrot-clean", metadata={"help": "Folder to save processed dataset."}
+ )
+ samples_per_file: Optional[int] = field(
+ default=100_000, metadata={"help": "Number of files to save per JSON output file."}
+ )
+ text_column: Optional[str] = field(default="content", metadata={"help": "Column containing text data to process."})
+ line_max: Optional[float] = field(
+ default=1000, metadata={"help": "Maximum line length in file, otherwise file is filtered."}
+ )
+ line_mean: Optional[float] = field(
+ default=100, metadata={"help": "Maximum mean line length in file, otherwise file is filtered."}
+ )
+ alpha_frac: Optional[float] = field(
+ default=0.25, metadata={"help": "Maximum fraction of non-alphanumeric characters, otherwise file is filtered."}
+ )
+ min_token_ratio: Optional[float] = field(
+ default=1.5, metadata={"help": "Minimum character token ratio for the file, otherwise file is filtered."}
+ )
+ filter_proba: Optional[float] = field(
+ default=0.7, metadata={"help": "Probability for filtering config, test and uncommon files."}
+ )
+ tokenizer: Optional[str] = field(
+ default="codeparrot/codeparrot",
+ metadata={"help": "Name or path to the tokenizer."},
+ )
+ near_deduplication: Optional[bool] = field(
+ default=False, metadata={"help": "If True, near-duplicate samples are removed."}
+ )
+ jaccard_threshold: Optional[float] = field(
+ default=0.85, metadata={"help": "Jaccard threshold for near-duplicate samples."}
+ )
+
+
+@dataclass
+class TokenizerTrainingArguments:
+ """
+ Configuration for tokenizer training.
+ """
+
+ base_tokenizer: Optional[str] = field(
+ default="openai-community/gpt2", metadata={"help": "Base tokenizer to build new tokenizer from."}
+ )
+ dataset_name: Optional[str] = field(
+ default="transformersbook/codeparrot-train", metadata={"help": "Dataset to train tokenizer on."}
+ )
+ text_column: Optional[str] = field(default="content", metadata={"help": "Column containing text data to process."})
+ vocab_size: Optional[int] = field(default=200_000, metadata={"help": "Number of examples to train tokenizer on."})
+ n_examples: Optional[int] = field(
+ default=32768, metadata={"help": "Number of examples to train the tokenizer on."}
+ )
+ tokenizer_name: Optional[str] = field(default="codeparrot", metadata={"help": "Name of new tokenizer."})
+ push_to_hub: Optional[bool] = field(default=True, metadata={"help": "Push saved tokenizer to the hub."})
+
+
+@dataclass
+class PretokenizationArguments:
+ """
+ Configuration for data pretokenization.
+ """
+
+ tokenizer_dir: Optional[str] = field(
+ default="codeparrot/codeparrot", metadata={"help": "Name or path to the tokenizer."}
+ )
+ dataset_name: Optional[str] = field(
+ default="codeparrot/codeparrot-clean-train", metadata={"help": "Name or path to the dataset to pretokenize."}
+ )
+ tokenized_data_repo: Optional[str] = field(
+ default="tokenized-codeparrot-train", metadata={"help": "Repo name of the pretokenized data."}
+ )
+ num_workers: Optional[int] = field(default=None, metadata={"help": "Number of workers used for code evaluation."})
+
+
+@dataclass
+class InitializationArguments:
+ """
+ Configuration for initializing new model.
+ """
+
+ config_name: Optional[str] = field(
+ default="openai-community/gpt2-large", metadata={"help": "Configuration to use for model initialization."}
+ )
+ tokenizer_name: Optional[str] = field(
+ default="codeparrot/codeparrot", metadata={"help": "Tokenizer attached to model."}
+ )
+ model_name: Optional[str] = field(default="codeparrot", metadata={"help": "Name of the created model."})
+ push_to_hub: Optional[bool] = field(default=True, metadata={"help": "Push saved tokenizer to the hub."})
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/bpe_training.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/bpe_training.py
new file mode 100644
index 0000000000000000000000000000000000000000..1cbeb4b4ee3240d7f49f661bd1947fa8a252a5a6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/bpe_training.py
@@ -0,0 +1,32 @@
+from arguments import TokenizerTrainingArguments
+from datasets import load_dataset
+from tqdm import tqdm
+
+from transformers import AutoTokenizer, HfArgumentParser
+from transformers.models.gpt2.tokenization_gpt2 import bytes_to_unicode
+
+
+# Iterator for Training
+def batch_iterator(batch_size=10):
+ for _ in tqdm(range(0, args.n_examples, batch_size)):
+ yield [next(iter_dataset)[args.text_column] for _ in range(batch_size)]
+
+
+# Configuration
+parser = HfArgumentParser(TokenizerTrainingArguments)
+args = parser.parse_args()
+
+# Base tokenizer
+tokenizer = AutoTokenizer.from_pretrained(args.base_tokenizer)
+base_vocab = list(bytes_to_unicode().values())
+
+# Load dataset
+dataset = load_dataset(args.dataset_name, split="train", streaming=True)
+iter_dataset = iter(dataset)
+
+
+# Training and saving
+new_tokenizer = tokenizer.train_new_from_iterator(
+ batch_iterator(), vocab_size=args.vocab_size, initial_alphabet=base_vocab
+)
+new_tokenizer.save_pretrained(args.tokenizer_name, push_to_hub=args.push_to_hub)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/codeparrot_training.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/codeparrot_training.py
new file mode 100644
index 0000000000000000000000000000000000000000..16f6077f2415c89455fe52addaf7109ede51df95
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/codeparrot_training.py
@@ -0,0 +1,328 @@
+import logging
+import os
+import time
+from argparse import Namespace
+from pathlib import Path
+
+import datasets
+import torch
+from accelerate import Accelerator, DistributedType
+from accelerate.utils import ProjectConfiguration
+from arguments import TrainingArguments
+from datasets import load_dataset
+from huggingface_hub import Repository
+from torch.optim import AdamW
+from torch.utils.data import IterableDataset
+from torch.utils.data.dataloader import DataLoader
+from torch.utils.data.datapipes.iter.combinatorics import ShufflerIterDataPipe
+
+import transformers
+from transformers import AutoModelForCausalLM, AutoTokenizer, HfArgumentParser, get_scheduler, set_seed
+
+
+class ConstantLengthDataset(IterableDataset):
+ """
+ Iterable dataset that returns constant length chunks of tokens from stream of text files.
+ Args:
+ tokenizer (Tokenizer): The processor used for proccessing the data.
+ dataset (dataset.Dataset): Dataset with text files.
+ infinite (bool): If True the iterator is reset after dataset reaches end else stops.
+ seq_length (int): Length of token sequences to return.
+ num_of_sequences (int): Number of token sequences to keep in buffer.
+ chars_per_token (int): Number of characters per token used to estimate number of tokens in text buffer.
+ tokenized (bool): If true we use a pretokenized dataset.
+ """
+
+ def __init__(
+ self,
+ tokenizer,
+ dataset,
+ infinite=False,
+ seq_length=1024,
+ num_of_sequences=1024,
+ chars_per_token=3.6,
+ tokenized=False,
+ ):
+ self.tokenizer = tokenizer
+ self.concat_token_id = tokenizer.bos_token_id
+ self.dataset = dataset
+ self.seq_length = seq_length
+ self.epoch = 0
+ self.infinite = infinite
+ self.current_size = 0
+ self.tokenized = tokenized
+
+ if self.tokenized:
+ self.max_buffer_size = seq_length * num_of_sequences
+ self.content_field = "input_ids"
+ else:
+ self.max_buffer_size = seq_length * chars_per_token * num_of_sequences
+ self.content_field = "content"
+
+ def __iter__(self):
+ iterator = iter(self.dataset)
+ more_examples = True
+ while more_examples:
+ buffer, buffer_len = [], 0
+ while True:
+ if buffer_len >= self.max_buffer_size:
+ break
+ try:
+ buffer.append(next(iterator)[self.content_field])
+ buffer_len += len(buffer[-1])
+ except StopIteration:
+ if self.infinite:
+ iterator = iter(self.dataset)
+ self.epoch += 1
+ logger.info(f"Dataset epoch: {self.epoch}")
+ else:
+ more_examples = False
+ break
+ if self.tokenized:
+ tokenized_inputs = buffer
+ else:
+ tokenized_inputs = self.tokenizer(buffer, truncation=False)["input_ids"]
+ all_token_ids = []
+ for tokenized_input in tokenized_inputs:
+ all_token_ids.extend(tokenized_input + [self.concat_token_id])
+ for i in range(0, len(all_token_ids), self.seq_length):
+ input_ids = all_token_ids[i : i + self.seq_length]
+ if len(input_ids) == self.seq_length:
+ self.current_size += 1
+ yield torch.tensor(input_ids)
+
+ def shuffle(self, buffer_size=1000):
+ return ShufflerIterDataPipe(self, buffer_size=buffer_size)
+
+
+def setup_logging(args):
+ project_name = args.model_ckpt.split("/")[-1]
+ logger = logging.getLogger(__name__)
+ log_dir = Path(args.save_dir) / "log/"
+ log_dir.mkdir(exist_ok=True)
+ filename = f"debug_{accelerator.process_index}.log"
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ handlers=[logging.FileHandler(log_dir / filename), logging.StreamHandler()],
+ )
+ if accelerator.is_main_process: # we only want to setup logging once
+ accelerator.init_trackers(project_name, vars(args))
+ run_name = accelerator.trackers[0].run.name
+ logger.setLevel(logging.INFO)
+ datasets.utils.logging.set_verbosity_info()
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ run_name = ""
+ logger.setLevel(logging.ERROR)
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+ return logger, run_name
+
+
+def create_dataloaders(args):
+ ds_kwargs = {"streaming": True}
+ train_data = load_dataset(args.dataset_name_train, split="train", **ds_kwargs)
+ train_data = train_data.shuffle(buffer_size=args.shuffle_buffer, seed=args.seed)
+ valid_data = load_dataset(args.dataset_name_valid, split="train", **ds_kwargs)
+ train_dataset = ConstantLengthDataset(
+ tokenizer, train_data, infinite=True, seq_length=args.seq_length, tokenized=args.tokenized
+ )
+ valid_dataset = ConstantLengthDataset(
+ tokenizer, valid_data, infinite=False, seq_length=args.seq_length, tokenized=args.tokenized
+ )
+ train_dataset = train_dataset.shuffle(buffer_size=args.shuffle_buffer)
+ train_dataloader = DataLoader(train_dataset, batch_size=args.train_batch_size, shuffle=True)
+ eval_dataloader = DataLoader(valid_dataset, batch_size=args.valid_batch_size)
+ return train_dataloader, eval_dataloader
+
+
+def get_grouped_params(model, args, no_decay=["bias", "ln_1.weight", "ln_2.weight", "ln_f.weight"]):
+ params_with_wd, params_without_wd = [], []
+ for n, p in model.named_parameters():
+ if any(nd in n for nd in no_decay):
+ params_without_wd.append(p)
+ else:
+ params_with_wd.append(p)
+ return [
+ {"params": params_with_wd, "weight_decay": args.weight_decay},
+ {"params": params_without_wd, "weight_decay": 0.0},
+ ]
+
+
+def log_metrics(step, metrics):
+ logger.info(f"Step {step}: {metrics}")
+ if accelerator.is_main_process:
+ accelerator.log(metrics, step)
+
+
+def compute_tflops(elapsed_time, accelerator, args):
+ # TFLOPs formula (from Equation 3 in Section 5.1 of https://arxiv.org/pdf/2104.04473.pdf).
+ config_model = accelerator.unwrap_model(model).config
+ checkpoint_factor = 4 if args.gradient_checkpointing else 3
+ batch_size = args.train_batch_size * accelerator.state.num_processes * args.gradient_accumulation_steps
+ factor = 24 * checkpoint_factor * batch_size * args.seq_length * config_model.n_layer * (config_model.n_embd**2)
+ flops_per_iteration = factor * (
+ 1.0
+ + (args.seq_length / (6.0 * config_model.n_embd))
+ + (tokenizer.vocab_size / (16.0 * config_model.n_layer * config_model.n_embd))
+ )
+ tflops = flops_per_iteration / (elapsed_time * accelerator.state.num_processes * (10**12))
+ return tflops
+
+
+def evaluate(args):
+ model.eval()
+ losses = []
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = model(batch, labels=batch)
+ loss = outputs.loss.repeat(args.valid_batch_size)
+ losses.append(accelerator.gather(loss))
+ if args.max_eval_steps > 0 and step >= args.max_eval_steps:
+ break
+ losses = torch.cat(losses)
+ loss = losses[: eval_dataloader.dataset.current_size].mean()
+ try:
+ perplexity = torch.exp(loss)
+ except OverflowError:
+ perplexity = float("inf")
+ return loss.item(), perplexity.item()
+
+
+# Settings
+parser = HfArgumentParser(TrainingArguments)
+args = parser.parse_args()
+
+# Accelerator
+config = ProjectConfiguration(project_dir=args.save_dir, logging_dir="log")
+accelerator = Accelerator(log_with=["wandb", "tensorboard"], project_config=config)
+acc_state = {str(k): str(v) for k, v in accelerator.state.__dict__.items()}
+
+args = Namespace(**vars(args), **acc_state)
+samples_per_step = accelerator.state.num_processes * args.train_batch_size
+set_seed(args.seed)
+
+# Clone model repository
+if accelerator.is_main_process:
+ hf_repo = Repository(args.save_dir, clone_from=args.model_ckpt)
+
+# Logging
+logger, run_name = setup_logging(args)
+logger.info(accelerator.state)
+
+# Checkout new branch on repo
+if accelerator.is_main_process:
+ hf_repo.git_checkout(run_name, create_branch_ok=True)
+
+# Load model and tokenizer
+model = AutoModelForCausalLM.from_pretrained(args.save_dir)
+if args.gradient_checkpointing:
+ model.gradient_checkpointing_enable()
+tokenizer = AutoTokenizer.from_pretrained(args.save_dir)
+
+# Load dataset and dataloader
+train_dataloader, eval_dataloader = create_dataloaders(args)
+
+# Prepare the optimizer and learning rate scheduler
+optimizer = AdamW(get_grouped_params(model, args), lr=args.learning_rate)
+lr_scheduler = get_scheduler(
+ name=args.lr_scheduler_type,
+ optimizer=optimizer,
+ num_warmup_steps=args.num_warmup_steps,
+ num_training_steps=args.max_train_steps,
+)
+accelerator.register_for_checkpointing(lr_scheduler)
+
+
+def get_lr():
+ return optimizer.param_groups[0]["lr"]
+
+
+# Prepare everything with our `accelerator`.
+model, optimizer, train_dataloader, eval_dataloader = accelerator.prepare(
+ model, optimizer, train_dataloader, eval_dataloader
+)
+
+# load in the weights and states from a previous save
+if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
+ accelerator.print(f"Resumed from checkpoint: {args.resume_from_checkpoint}")
+ accelerator.load_state(args.resume_from_checkpoint)
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = [f.name for f in os.scandir(args.save_dir) if f.is_dir() and "step" in str(f)]
+ dirs.sort(key=os.path.getctime)
+ path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
+ # Extract the step of the checkpoint to continue from there
+ training_difference = os.path.splitext(path)[0]
+ resume_step = int(training_difference.replace("step_", ""))
+
+# Train model
+model.train()
+completed_steps = 0
+t_start = time.time()
+loss_tracking = 0
+for step, batch in enumerate(train_dataloader, start=1):
+ if args.resume_from_checkpoint and step < resume_step:
+ continue # we need to skip steps until we reach the resumed step
+ loss = model(batch, labels=batch, use_cache=False).loss
+ avg_loss = accelerator.gather(loss.repeat(args.train_batch_size)).mean()
+ loss_tracking += avg_loss.item() / args.gradient_accumulation_steps
+ log_metrics(step, {"samples": step * samples_per_step, "loss_per_step/train": loss.item()})
+ loss = loss / args.gradient_accumulation_steps
+ if step % args.gradient_accumulation_steps != 0:
+ # Prevent backward from doing gradient all_reduce in every step
+ if accelerator.distributed_type == DistributedType.MULTI_GPU:
+ with model.no_sync():
+ accelerator.backward(loss)
+ else:
+ accelerator.backward(loss)
+ else:
+ lr = get_lr()
+ accelerator.backward(loss)
+ accelerator.clip_grad_norm_(model.parameters(), 1.0)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ elapsed_time = time.time() - t_start
+ tflops = compute_tflops(elapsed_time, accelerator, args)
+ log_metrics(
+ step,
+ {
+ "steps": completed_steps,
+ "loss/train": loss_tracking,
+ "lr": lr,
+ "tflops": tflops,
+ "time_per_iteration": elapsed_time,
+ },
+ )
+ t_start = time.time()
+ loss_tracking = 0
+ completed_steps += 1
+ if step % args.save_checkpoint_steps == 0:
+ logger.info("Evaluating and saving model checkpoint")
+ eval_loss, perplexity = evaluate(args)
+ log_metrics(step, {"loss/eval": eval_loss, "perplexity": perplexity})
+ accelerator.wait_for_everyone()
+ save_dir = os.path.join(args.save_dir, f"step_{step}")
+ accelerator.save_state(save_dir)
+ if accelerator.is_main_process:
+ hf_repo.push_to_hub(commit_message=f"step {step}")
+ model.train()
+ if completed_steps >= args.max_train_steps:
+ break
+
+# Evaluate and save the last checkpoint
+logger.info("Evaluating and saving model after training")
+eval_loss, perplexity = evaluate(args)
+log_metrics(step, {"loss/eval": eval_loss, "perplexity": perplexity})
+accelerator.wait_for_everyone()
+unwrapped_model = accelerator.unwrap_model(model)
+unwrapped_model.save_pretrained(args.save_dir, save_function=accelerator.save)
+save_dir = os.path.join(args.save_dir, f"step_{step}")
+accelerator.save_state(save_dir)
+if accelerator.is_main_process:
+ hf_repo.push_to_hub(commit_message="final model")
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/human_eval.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/human_eval.py
new file mode 100644
index 0000000000000000000000000000000000000000..ef217a597e338550ae9e419e1abd01a6cf76a633
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/human_eval.py
@@ -0,0 +1,228 @@
+import json
+import multiprocessing
+import os
+import re
+from collections import defaultdict
+
+import torch
+from accelerate import Accelerator
+from accelerate.utils import set_seed
+from arguments import HumanEvalArguments
+from datasets import load_dataset, load_metric
+from torch.utils.data import IterableDataset
+from torch.utils.data.dataloader import DataLoader
+from tqdm import tqdm
+
+import transformers
+from transformers import AutoModelForCausalLM, AutoTokenizer, HfArgumentParser, StoppingCriteria, StoppingCriteriaList
+
+
+EOF_STRINGS = ["\nclass", "\ndef", "\n#", "\n@", "\nprint", "\nif"]
+
+
+class TokenizedDataset(IterableDataset):
+ """Tokenize and preprocess the dataset
+ Multiple copies of the same prompt are sent sequentially.
+ See compute_code for more details.
+ """
+
+ def __init__(self, tokenizer, dataset, n_tasks=None, n_copies=1):
+ self.tokenizer = tokenizer
+ self.dataset = dataset
+ self.n_tasks = len(dataset) if n_tasks is None else n_tasks
+ self.n_copies = n_copies
+
+ def __iter__(self):
+ prompts = []
+ for task in range(self.n_tasks):
+ # without strip, the model generate commented codes ...
+ prompts.append(self.tokenizer.eos_token + self.dataset[task]["prompt"].strip())
+ outputs = self.tokenizer(prompts, padding=True, return_tensors="pt")
+ for task in range(self.n_tasks):
+ for _ in range(self.n_copies):
+ yield {
+ "ids": outputs.input_ids[task],
+ "task_id": task,
+ "input_len": outputs.attention_mask[task].sum(),
+ }
+
+
+class EndOfFunctionCriteria(StoppingCriteria):
+ """Custom `StoppingCriteria` which checks if all generated functions in the batch are completed."""
+
+ def __init__(self, start_length, eof_strings, tokenizer):
+ self.start_length = start_length
+ self.eof_strings = eof_strings
+ self.tokenizer = tokenizer
+
+ def __call__(self, input_ids, scores, **kwargs):
+ """Returns true if all generated sequences contain any of the end-of-function strings."""
+ decoded_generations = self.tokenizer.batch_decode(input_ids[:, self.start_length :])
+ done = []
+ for decoded_generation in decoded_generations:
+ done.append(any(stop_string in decoded_generation for stop_string in self.eof_strings))
+ return all(done)
+
+
+def remove_last_block(string):
+ """Remove the last block of the code containing EOF_STRINGS"""
+ string_list = re.split("(%s)" % "|".join(EOF_STRINGS), string)
+ # last string should be ""
+ return "".join(string_list[:-2])
+
+
+def complete_code(accelerator, model, tokenizer, dataloader, n_tasks, batch_size=20, **gen_kwargs):
+ """Generate multiple codes for each task in the dataset. This function leverage accelerator to distribute
+ the processing to multiple GPUs.
+ dataloader, a wrapper around a TokenizeDataset objectm is supposed to send all the prompts from
+ the evalution dataset to the modelm as the following:
+ [p_0_0, p_0_1, ..., p_0_nc-1, p_1_0, ..., p_nt-1_nc-1]
+ where nc is the number of copies of the prompt, and nt is the number of tasks.
+ nc is such that num_sample = nc * batch_size
+
+ Parameters
+ ----------
+ accelerator: Accelerator
+
+ model: transformers.PreTrainedModel
+ Code generation model. AutoTokenizer.from_pretrained(model_ckpt), ex model_ckpt = "lvwerra/codeparrot"
+
+ tokenizer: transformers.AutoTokenizer
+ The tokenizer used to train model
+
+ dataloader: DataLoader
+ The dataloader is a wrapper around a TokenizeDataset object. It is designed to be used with multiple GPUs.
+
+ n_tasks: int
+ The number of tasks in the dataset. It is used to determine the length of the output.
+ Should be aligned with the number of tasks in the TokenizeDataset.
+
+ batch_size: int
+ num_return_sequences per copy of the prompt such that num_sample = batch_size * n_copies
+
+ gen_kwargs: dict
+ Keyword arguments for the generation function of the model.
+
+ Returns
+ -------
+ code_gens: list of list of str, of length n_tasks
+ List of generated codes for each task.
+ Each element is a list of generated codes for each task, with length num_samples
+ """
+ gen_token_dict = defaultdict(list) # dict of list of generated tokens
+ for step, batch in tqdm(enumerate(dataloader)):
+ with torch.no_grad():
+ gen_kwargs["stopping_criteria"][0].start_length = batch["ids"].shape[-1]
+ generated_tokens = accelerator.unwrap_model(model).generate(
+ input_ids=batch["ids"][:, : batch["input_len"]], num_return_sequences=batch_size, **gen_kwargs
+ )
+ # each task is generated batch_size times
+ generated_tasks = batch["task_id"].repeat(batch_size)
+ generated_tokens = accelerator.pad_across_processes(
+ generated_tokens, dim=1, pad_index=tokenizer.pad_token_id
+ )
+
+ generated_tokens, generated_tasks = accelerator.gather((generated_tokens, generated_tasks))
+ generated_tokens = generated_tokens.cpu().numpy()
+ generated_tasks = generated_tasks.cpu().numpy()
+
+ for task, generated_tokens in zip(generated_tasks, generated_tokens):
+ gen_token_dict[task].append(generated_tokens)
+
+ code_gens = [[] for _ in range(n_tasks)]
+ for task, generated_tokens in gen_token_dict.items():
+ for s in generated_tokens:
+ gen_code = tokenizer.decode(s, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+ code_gens[task].append(remove_last_block(gen_code))
+ return code_gens
+
+
+def main():
+ # Setup configuration
+ parser = HfArgumentParser(HumanEvalArguments)
+ args = parser.parse_args()
+
+ transformers.logging.set_verbosity_error()
+ # enables code execution in code_eval metric
+ os.environ["HF_ALLOW_CODE_EVAL"] = args.HF_ALLOW_CODE_EVAL
+ # make sure tokenizer plays nice with multiprocessing
+ os.environ["TOKENIZERS_PARALLELISM"] = "false"
+
+ if args.num_workers is None:
+ args.num_workers = multiprocessing.cpu_count()
+
+ # Use dataset load to feed to accelerate
+ accelerator = Accelerator()
+ set_seed(args.seed, device_specific=True)
+
+ # Load model and tokenizer
+ tokenizer = AutoTokenizer.from_pretrained(args.model_ckpt)
+ tokenizer.pad_token = tokenizer.eos_token
+ model = AutoModelForCausalLM.from_pretrained(args.model_ckpt)
+
+ # Generation settings
+ gen_kwargs = {
+ "do_sample": args.do_sample,
+ "temperature": args.temperature,
+ "max_new_tokens": args.max_new_tokens,
+ "top_p": args.top_p,
+ "top_k": args.top_k,
+ "stopping_criteria": StoppingCriteriaList([EndOfFunctionCriteria(0, EOF_STRINGS, tokenizer)]),
+ }
+
+ # Load evaluation dataset and metric
+ human_eval = load_dataset("openai_humaneval")
+ code_eval_metric = load_metric("code_eval")
+
+ n_tasks = args.num_tasks if args.num_tasks is not None else len(human_eval["test"])
+ n_copies = args.n_samples // args.batch_size
+
+ human_eval_tokenized = TokenizedDataset(tokenizer, human_eval["test"], n_copies=n_copies, n_tasks=n_tasks)
+ # do not confuse args.batch_size, which is actually the num_return_sequences
+ human_eval_loader = DataLoader(human_eval_tokenized, batch_size=1)
+
+ # Run a quick test to see if code evaluation is enabled
+ try:
+ _ = code_eval_metric.compute(references=[""], predictions=[[""]])
+ except ValueError as exception:
+ print(
+ 'Code evaluation not enabled. Read the warning below carefully and then use `--HF_ALLOW_CODE_EVAL="1"`'
+ " flag to enable code evaluation."
+ )
+ raise exception
+
+ model, human_eval_loader = accelerator.prepare(model, human_eval_loader)
+
+ generations = complete_code(
+ accelerator,
+ model,
+ tokenizer,
+ human_eval_loader,
+ n_tasks=n_tasks,
+ batch_size=args.batch_size,
+ **gen_kwargs,
+ )
+
+ if accelerator.is_main_process:
+ references = []
+
+ for task in tqdm(range(n_tasks)):
+ test_func = human_eval["test"][task]["test"]
+ entry_point = f"check({human_eval['test'][task]['entry_point']})"
+ references.append("\n" + test_func + "\n" + entry_point)
+
+ # Evaluate completions with "code_eval" metric
+ pass_at_k, _ = code_eval_metric.compute(
+ references=references, predictions=generations, num_workers=args.num_workers
+ )
+ print(f"Results: {pass_at_k}")
+
+ # Save results to json file
+ with open(args.output_file, "w") as fp:
+ json.dump(pass_at_k, fp)
+
+
+# For some reason the folliwng seems to be necessary sometimes for code_eval to work nice with multiprocessing
+# https://stackoverflow.com/questions/60804599/python-multiprocessing-keeps-spawning-the-whole-script
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/initialize_model.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/initialize_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..6bf028688f12627b23f5fb2236ad403d7c9e6442
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/initialize_model.py
@@ -0,0 +1,27 @@
+from arguments import InitializationArguments
+
+from transformers import AutoConfig, AutoModelForCausalLM, AutoTokenizer, HfArgumentParser
+
+
+# Configuration
+parser = HfArgumentParser(InitializationArguments)
+args = parser.parse_args()
+
+# Load codeparrot tokenizer trained for Python code tokenization
+tokenizer = AutoTokenizer.from_pretrained(args.tokenizer_name)
+
+# Config: "scale_attn_by_layer_idx" and "reorder_and_upcast_attn" are Mistral stability tweaks
+config_kwargs = {
+ "vocab_size": len(tokenizer),
+ "scale_attn_by_inverse_layer_idx": True,
+ "reorder_and_upcast_attn": True,
+}
+
+# Load model config (GPT-2 large in this case)
+config = AutoConfig.from_pretrained(args.config_name, **config_kwargs)
+
+# Initialize new model with config
+model = AutoModelForCausalLM.from_config(config)
+
+# Save model to the hub
+model.save_pretrained(args.model_name, push_to_hub=args.push_to_hub)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/minhash_deduplication.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/minhash_deduplication.py
new file mode 100644
index 0000000000000000000000000000000000000000..f1984711278a105f8cabf65218c4448ec6357670
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/minhash_deduplication.py
@@ -0,0 +1,268 @@
+import json
+import multiprocessing as mp
+import re
+from collections import defaultdict
+from functools import partial
+from typing import Dict, List, Optional, Set, Tuple, Type
+
+from datasets import Dataset
+from datasketch import MinHash, MinHashLSH
+from dpu_utils.utils.iterators import ThreadedIterator
+from tqdm import tqdm
+
+
+NON_ALPHA = re.compile("[^A-Za-z_0-9]")
+# parameters used in DuplicationIndex
+MIN_NUM_TOKENS = 10
+NUM_PERM = 256
+
+
+def get_min_hash(tokens: List[str]) -> Optional[MinHash]:
+ """Compute the MinHash of a code snippet."""
+ if len(tokens) < MIN_NUM_TOKENS:
+ return None
+ min_hash = MinHash(num_perm=NUM_PERM)
+ for token in set(tokens):
+ min_hash.update(token.encode())
+ return min_hash
+
+
+def get_tokens(code: str) -> Set[str]:
+ """Tokenize a code snippet."""
+ return {t for t in NON_ALPHA.split(code) if len(t.strip()) > 0}
+
+
+class DuplicationIndex:
+ def __init__(
+ self,
+ *,
+ duplication_jaccard_threshold: float = 0.85,
+ ):
+ self._duplication_jaccard_threshold = duplication_jaccard_threshold
+ self._num_perm = NUM_PERM
+ self._index = MinHashLSH(threshold=self._duplication_jaccard_threshold, num_perm=self._num_perm)
+
+ self._duplicate_clusters = defaultdict(set)
+
+ def add(self, code_key: Tuple, min_hash: MinHash) -> None:
+ """Add a key to _index (MinHashLSH)
+ the min_hash is used to query closest matches based on the jaccard_threshold.
+ The new key is either added to a existing cluster of one close match,
+ or a new cluster is created. The clusters created in this way, depend on the order of add.
+
+ Args:
+ code_key (Tuple of (index, repo_name, path)):
+ Theoritically any hasbale key. Here we use a tuple to retrieve the information later.
+ min_hash: MinHash of the code_key.
+ """
+ close_duplicates = self._index.query(min_hash)
+ if code_key in self._index.keys:
+ print(f"Duplicate key {code_key}")
+ return
+
+ self._index.insert(code_key, min_hash)
+ if len(close_duplicates) > 0:
+ for base_duplicate in close_duplicates:
+ if base_duplicate in self._duplicate_clusters:
+ self._duplicate_clusters[base_duplicate].add(code_key)
+ break
+ else:
+ self._duplicate_clusters[close_duplicates[0]].add(code_key)
+
+ def get_duplicate_clusters(self) -> List[List[Dict]]:
+ """Export the duplicate clusters.
+ For each cluster, the first element is the base element of the cluster.
+ The base element has an estimation jaccard similarity higher than the threshold with all the other elements.
+
+ Returns:
+ duplicate_clusters (List[List[Dict]]):
+ List of duplicate clusters.
+ """
+ duplicate_clusters = []
+ for base, duplicates in self._duplicate_clusters.items():
+ cluster = [base] + list(duplicates)
+ # reformat the cluster to be a list of dict
+ cluster = [{"base_index": el[0], "repo_name": el[1], "path": el[2]} for el in cluster]
+ duplicate_clusters.append(cluster)
+ return duplicate_clusters
+
+ def save(self, filepath) -> None:
+ duplicate_clusters = self.get_duplicate_clusters()
+ with open(filepath, "w") as f:
+ json.dump(duplicate_clusters, f)
+
+
+def _compute_min_hash(element):
+ index, data = element
+ min_hash = get_min_hash([t for t in NON_ALPHA.split(data["content"]) if len(t.strip()) > 0])
+ if min_hash is not None:
+ return (index, data["repo_name"], data["path"]), min_hash
+
+
+def minhash_iter(dataset_iterator: Type[Dataset]):
+ with mp.Pool() as pool:
+ for data in pool.imap_unordered(
+ _compute_min_hash,
+ ThreadedIterator(dataset_iterator, max_queue_size=10000),
+ chunksize=100,
+ ):
+ if data is not None:
+ yield data
+
+
+def make_duplicate_clusters(dataset_iterator: Type[Dataset], jaccard_threshold: float):
+ """Find duplicate clusters in the dataset in two steps:
+ 1. Compute MinHash for each code snippet. MinHash is a tool for fast jaccard similarity estimation.
+ This step is computed using an asynchronous multiprocessing pool, minhash_iter
+ 2. Find duplicate clusters. The computed MinHash is added sequentially to the DuplicationIndex.
+ This step cannot be parallelized. So using asynchronous thread in the previous step helps to speed up the process.
+ """
+ di = DuplicationIndex(duplication_jaccard_threshold=jaccard_threshold)
+
+ for filename, min_hash in tqdm(ThreadedIterator(minhash_iter(enumerate(dataset_iterator)), max_queue_size=100)):
+ di.add(filename, min_hash)
+
+ # Returns a List[Cluster] where Cluster is List[str] with the filenames.
+ return di.get_duplicate_clusters()
+
+
+def jaccard_similarity(code1: str, code2: str) -> float:
+ """Compute the Jaccard similarity of two code snippets."""
+ tokens1 = get_tokens(code1)
+ tokens2 = get_tokens(code2)
+ return len(tokens1 & tokens2) / len(tokens1 | tokens2)
+
+
+_shared_dataset = None
+
+
+def _find_cluster_extremes_shared(cluster, jaccard_threshold):
+ """Find a reduced cluster such that each code in the origin cluster is similar to at least one code in the reduced cluster.
+ Two codes are similar if their Jaccard similarity is above the threshold.
+
+ Args:
+ cluster (List[dict]):
+ cluster is a list of dict, each dict contains the following keys:
+ - base_index
+ - repo_name
+ - path
+ This is a typical output of DuplicationIndex.get_duplicate_clusters()
+ jaccard_threshold (float):
+ threshold for Jaccard similarity.
+ Two codes are similar if their Jaccard similarity is above the threshold.
+
+ Returns:
+ extremes (List[dict]):
+ A reduced representation of the cluster. The field copies is added to each dict.
+ The copies field indicates the number of similar codes in the cluster for a extreme.
+ """
+ extremes = []
+ for element1 in cluster:
+ code1 = _shared_dataset[element1["base_index"]]["content"]
+ for element2 in extremes:
+ code2 = _shared_dataset[element2["base_index"]]["content"]
+ if jaccard_similarity(code1, code2) >= jaccard_threshold:
+ element2["copies"] += 1
+ break
+ else:
+ element1["copies"] = 1
+ extremes.append(element1)
+ return extremes
+
+
+def find_extremes(cluster_list, dataset, jaccard_threshold):
+ """Call the _find_cluster_extremes_shared function in a parallel fashion.
+
+ Args:
+ cluster_list (List[List[Dict]]):
+ each cluster is a list of dicts with the key base_index,
+ referring to the index of the base code in the dataset.
+ dataset (Type[Dataset]):
+ dataset is used to access the content of the code snippets,
+ using the base_index from the cluster_list.
+ dataset is shared between all the processes using a glabal variable (any other way to share the dataset?),
+ otherwise the multi processing is not speeded up.
+ jaccard_threshold (float):
+ the threshold for the jaccard similarity. The default value is 0.85
+
+ Returns:
+ extremes_list (List[Dict]):
+ Each cluster is reduced to extremes.
+ See _find_cluster_extremes_shared for the definition of extremes.
+ """
+ global _shared_dataset
+ _shared_dataset = dataset
+ extremes_list = []
+ f = partial(_find_cluster_extremes_shared, jaccard_threshold=jaccard_threshold)
+ with mp.Pool() as pool:
+ for extremes in tqdm(
+ pool.imap_unordered(
+ f,
+ cluster_list,
+ ),
+ total=len(cluster_list),
+ ):
+ extremes_list.append(extremes)
+ return extremes_list
+
+
+def deduplicate_dataset(
+ dataset: Type[Dataset], jaccard_threshold: float = 0.85
+) -> Tuple[Type[Dataset], List[List[Dict]]]:
+ """Deduplicate the dataset using minhash and jaccard similarity.
+ This function first generate duplicate clusters, then each cluster
+ is reduced to the extremes that are similar to the other elements in the cluster.
+ Codes are called similar if their Jaccard similarity is greater than jaccard_threshold (0.85 default).
+
+ Args:
+ dataset (Type[Dataset]):
+ The dataset to deduplicate.
+ jaccard_threshold (float, default=0.85):
+ jaccard threshold to determine if two codes are similar
+
+ Returns:
+ ds_dedup (Type[Dataset]):
+ The deduplicated dataset.
+ duplicate_clusters (List[List[Dict]]):
+ The list of duplicate clusters.
+ Each cluster is a list of dicts with the following keys:
+ - base_index : int
+ The index of the code in the original dataset.
+ - repo_name : str
+ - path : str
+ - copies : int
+ The number of copies of the code in the cluster. (find_cluster_extremes)
+ - is_extreme : bool
+ Whether the code is an extreme in the cluster.
+ All the codes in the cluster are removed from the dataset except the extremes.
+
+ Example:
+ >>> from datasets import load_dataset
+ >>> from minhash_deduplication import deduplicate_dataset
+ >>> ds = load_dataset("lvwerra/codeparrot-clean", split="train")
+ >>> ds_dedup, duplicate_clusters = deduplicate_dataset(ds, jaccard_threshold=0.85)
+ """
+ duplicate_clusters = make_duplicate_clusters(dataset, jaccard_threshold)
+ duplicate_indices = {x["base_index"] for cluster in duplicate_clusters for x in cluster}
+ extreme_dict = {}
+ extremes_clusters = find_extremes(duplicate_clusters, dataset, jaccard_threshold)
+ for extremes in extremes_clusters:
+ for element in extremes:
+ extreme_dict[element["base_index"]] = element
+ remove_indices = duplicate_indices - set(extreme_dict.keys())
+ ds_filter = dataset.filter(lambda x, idx: idx not in remove_indices, with_indices=True)
+
+ # update duplicate_clusters
+ for cluster in duplicate_clusters:
+ for element in cluster:
+ element["is_extreme"] = element["base_index"] in extreme_dict
+ if element["is_extreme"]:
+ element["copies"] = extreme_dict[element["base_index"]]["copies"]
+
+ print(f"Original dataset size: {len(dataset)}")
+ print(f"Number of duplicate clusters: {len(duplicate_clusters)}")
+ print(f"Files in duplicate cluster: {len(duplicate_indices)}")
+ print(f"Unique files in duplicate cluster: {len(extreme_dict)}")
+ print(f"Filtered dataset size: {len(ds_filter)}")
+
+ return ds_filter, duplicate_clusters
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/preprocessing.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/preprocessing.py
new file mode 100644
index 0000000000000000000000000000000000000000..d9cac5abfd8e197756b64118cc5bba1e42863a63
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/preprocessing.py
@@ -0,0 +1,215 @@
+import gzip
+import json
+import multiprocessing
+import os
+import re
+import shutil
+import time
+from pathlib import Path
+
+import numpy as np
+from arguments import PreprocessingArguments
+from datasets import load_dataset
+from huggingface_hub.utils import insecure_hashlib
+from minhash_deduplication import deduplicate_dataset
+
+from transformers import AutoTokenizer, HfArgumentParser
+
+
+PATTERN = re.compile(r"\s+")
+
+
+def get_hash(example):
+ """Get hash of content field."""
+ return {"hash": insecure_hashlib.md5(re.sub(PATTERN, "", example["content"]).encode("utf-8")).hexdigest()}
+
+
+def line_stats(example):
+ """Calculates mean and max line length of file."""
+ line_lengths = [len(line) for line in example["content"].splitlines()]
+ return {"line_mean": np.mean(line_lengths), "line_max": max(line_lengths)}
+
+
+def alpha_stats(example):
+ """Calculates mean and max line length of file."""
+ alpha_frac = np.mean([c.isalnum() for c in example["content"]])
+ return {"alpha_frac": alpha_frac}
+
+
+def check_uniques(example, uniques):
+ """Check if current hash is still in set of unique hashes and remove if true."""
+ if example["hash"] in uniques:
+ uniques.remove(example["hash"])
+ return True
+ else:
+ return False
+
+
+def is_autogenerated(example, scan_width=5):
+ """Check if file is autogenerated by looking for keywords in the first few lines of the file."""
+ keywords = ["auto-generated", "autogenerated", "automatically generated"]
+ lines = example["content"].splitlines()
+ for _, line in zip(range(scan_width), lines):
+ for keyword in keywords:
+ if keyword in line.lower():
+ return {"autogenerated": True}
+ else:
+ return {"autogenerated": False}
+
+
+def is_config_or_test(example, scan_width=5, coeff=0.05):
+ """Check if file is a configuration file or a unit test by :
+ 1- looking for keywords in the first few lines of the file.
+ 2- counting number of occurrence of the words 'config' and 'test' with respect to number of lines.
+ """
+
+ keywords = ["unit tests", "test file", "configuration file"]
+ lines = example["content"].splitlines()
+ count_config = 0
+ count_test = 0
+ # first test
+ for _, line in zip(range(scan_width), lines):
+ for keyword in keywords:
+ if keyword in line.lower():
+ return {"config_or_test": True}
+ # second test
+ nlines = example["content"].count("\n")
+ threshold = int(coeff * nlines)
+ for line in lines:
+ count_config += line.lower().count("config")
+ count_test += line.lower().count("test")
+ if count_config > threshold or count_test > threshold:
+ return {"config_or_test": True}
+ return {"config_or_test": False}
+
+
+def has_no_keywords(example):
+ """Check if a python file has none of the keywords for: funcion, class, for loop, while loop."""
+ keywords = ["def ", "class ", "for ", "while "]
+ lines = example["content"].splitlines()
+ for line in lines:
+ for keyword in keywords:
+ if keyword in line.lower():
+ return {"has_no_keywords": False}
+ return {"has_no_keywords": True}
+
+
+def has_few_assignments(example, minimum=4):
+ """Check if file uses symbol '=' less than `minimum` times."""
+ lines = example["content"].splitlines()
+ counter = 0
+ for line in lines:
+ counter += line.lower().count("=")
+ if counter > minimum:
+ return {"has_few_assignments": False}
+ return {"has_few_assignments": True}
+
+
+def char_token_ratio(example):
+ """Compute character/token ratio of the file with tokenizer."""
+ input_ids = tokenizer(example["content"], truncation=False)["input_ids"]
+ ratio = len(example["content"]) / len(input_ids)
+ return {"ratio": ratio}
+
+
+def preprocess(example):
+ """Chain all preprocessing steps into one function to not fill cache."""
+ results = {}
+ results.update(get_hash(example))
+ results.update(line_stats(example))
+ results.update(alpha_stats(example))
+ results.update(char_token_ratio(example))
+ results.update(is_autogenerated(example))
+ results.update(is_config_or_test(example))
+ results.update(has_no_keywords(example))
+ results.update(has_few_assignments(example))
+ return results
+
+
+def filter(example, uniques, args):
+ """Filter dataset with heuristics. Config, test and has_no_keywords files are removed with a given probability."""
+ if not check_uniques(example, uniques):
+ return False
+ elif example["autogenerated"]:
+ return False
+ elif example["line_max"] > args.line_max:
+ return False
+ elif example["line_mean"] > args.line_mean:
+ return False
+ elif example["alpha_frac"] < args.alpha_frac:
+ return False
+ elif example["ratio"] < args.min_token_ratio:
+ return False
+ elif example["config_or_test"] and np.random.rand() <= args.filter_proba:
+ return False
+ elif example["has_no_keywords"] and np.random.rand() <= args.filter_proba:
+ return False
+ elif example["has_few_assignments"]:
+ return False
+ else:
+ return True
+
+
+def compress_file(file_path):
+ """Compress a file with g-zip."""
+ with open(file_path, "rb") as f_in:
+ with gzip.open(str(file_path) + ".gz", "wb", compresslevel=6) as f_out:
+ shutil.copyfileobj(f_in, f_out)
+ os.unlink(file_path)
+
+
+# Settings
+parser = HfArgumentParser(PreprocessingArguments)
+args = parser.parse_args()
+if args.num_workers is None:
+ args.num_workers = multiprocessing.cpu_count()
+tokenizer = AutoTokenizer.from_pretrained(args.tokenizer_dir)
+
+# Load dataset
+t_start = time.time()
+ds = load_dataset(args.dataset_name, split="train")
+print(f"Time to load dataset: {time.time()-t_start:.2f}")
+
+# Run preprocessing
+t_start = time.time()
+ds = ds.map(preprocess, num_proc=args.num_workers)
+print(f"Time to preprocess dataset: {time.time()-t_start:.2f}")
+
+# Deduplicate hashes
+uniques = set(ds.unique("hash"))
+frac = len(uniques) / len(ds)
+print(f"Fraction of duplicates: {1-frac:.2%}")
+
+# Deduplicate data and apply heuristics
+t_start = time.time()
+ds_filter = ds.filter(filter, fn_kwargs={"uniques": uniques, "args": args})
+print(f"Time to filter dataset: {time.time()-t_start:.2f}")
+print(f"Size of filtered dataset: {len(ds_filter)}")
+
+# Deduplicate with minhash and jaccard similarity
+if args.near_deduplication:
+ t_start = time.time()
+ ds_filter, duplicate_clusters = deduplicate_dataset(ds_filter, args.jaccard_threshold)
+ print(f"Time to deduplicate dataset: {time.time()-t_start:.2f}")
+ print(f"Size of deduplicate dataset: {len(ds_filter)}")
+
+# Save data in batches of samples_per_file
+output_dir = Path(args.output_dir)
+output_dir.mkdir(exist_ok=True)
+
+# save duplicate_clusters in the output_dir as artifacts
+# not sure it is the right place the save it
+if args.near_deduplication:
+ with open(output_dir / "duplicate_clusters.json", "w") as f:
+ json.dump(duplicate_clusters, f)
+
+data_dir = output_dir / "data"
+data_dir.mkdir(exist_ok=True)
+
+t_start = time.time()
+for file_number, index in enumerate(range(0, len(ds_filter), args.samples_per_file)):
+ file_path = str(data_dir / f"file-{file_number+1:012}.json")
+ end_index = min(len(ds_filter), index + args.samples_per_file)
+ ds_filter.select(list(range(index, end_index))).to_json(file_path)
+ compress_file(file_path)
+print(f"Time to save dataset: {time.time()-t_start:.2f}")
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/pretokenizing.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/pretokenizing.py
new file mode 100644
index 0000000000000000000000000000000000000000..7cac8f511918d1accc4e855ed6283f211ef6fbc4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/pretokenizing.py
@@ -0,0 +1,49 @@
+import multiprocessing
+import time
+
+from arguments import PretokenizationArguments
+from datasets import load_dataset
+
+from transformers import AutoTokenizer, HfArgumentParser
+
+
+def tokenize(example):
+ output = {}
+ output["input_ids"] = tokenizer(example["content"], truncation=False)["input_ids"]
+ output["ratio_char_token"] = len(example["content"]) / len(output["input_ids"])
+ return output
+
+
+parser = HfArgumentParser(PretokenizationArguments)
+args = parser.parse_args()
+if args.num_workers is None:
+ args.num_workers = multiprocessing.cpu_count()
+tokenizer = AutoTokenizer.from_pretrained(args.tokenizer_dir)
+
+t_start = time.time()
+ds = load_dataset(args.dataset_name, split="train")
+print(f"Dataset loaded in {time.time()-t_start:.2f}s")
+
+t_start = time.time()
+ds = ds.map(
+ tokenize,
+ num_proc=args.num_workers,
+ remove_columns=[
+ "repo_name",
+ "path",
+ "copies",
+ "size",
+ "content",
+ "license",
+ "hash",
+ "line_mean",
+ "line_max",
+ "alpha_frac",
+ "autogenerated",
+ ],
+)
+print(f"Dataset tokenized in {time.time()-t_start:.2f}s")
+
+t_start = time.time()
+ds.push_to_hub(args.tokenized_data_repo)
+print(f"Data pushed to the hub in {time.time()-t_start:.2f}s")
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/tests/__init__.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/tests/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/tests/test_deduplicate.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/tests/test_deduplicate.py
new file mode 100644
index 0000000000000000000000000000000000000000..aaf53de137f4905565738ce9eafca15cc755a2fb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/tests/test_deduplicate.py
@@ -0,0 +1,29 @@
+from unittest import TestCase
+
+from datasets import Dataset
+from minhash_deduplication import deduplicate_dataset, make_duplicate_clusters
+
+
+def get_dataset():
+ data_dict = {
+ "repo_name": ["test_repo1", "test_repo2", "test_repo3"],
+ "path": ["test_1.py", "test_2.py", "unit_test.py"],
+ "content": ["a " * 20, "a " * 30, "b " * 7],
+ }
+ dataset = Dataset.from_dict(data_dict)
+ return dataset
+
+
+class MakeDuplicateClustersTest(TestCase):
+ def test_make_duplicate_clusters(self):
+ ds = get_dataset()
+ duplicate_clusters = make_duplicate_clusters(ds, 0.85)
+ self.assertEqual(len(duplicate_clusters[0]), 2)
+
+ def test_deduplicate_dataset(self):
+ ds = get_dataset()
+ ds_filter, duplicate_clusters = deduplicate_dataset(ds)
+ self.assertEqual(len(ds_filter), 2)
+ print(duplicate_clusters)
+ self.assertEqual(duplicate_clusters[0][0]["copies"], 2)
+ self.assertEqual(duplicate_clusters[0][0]["is_extreme"], True)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/validation_loss.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/validation_loss.py
new file mode 100644
index 0000000000000000000000000000000000000000..929c2df427e227d70eb69ad9394d300d64e85bc5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/codeparrot/scripts/validation_loss.py
@@ -0,0 +1,99 @@
+import logging
+
+import torch
+from accelerate import Accelerator
+from arguments import EvaluationArguments
+from datasets import load_dataset
+from torch.utils.data import IterableDataset
+from torch.utils.data.dataloader import DataLoader
+
+from transformers import AutoModelForCausalLM, AutoTokenizer, HfArgumentParser, set_seed
+
+
+class ConstantLengthDataset(IterableDataset):
+ def __init__(self, tokenizer, dataset, seq_length=1024, num_of_sequences=1024, chars_per_token=3.6):
+ self.tokenizer = tokenizer
+ self.concat_token_id = tokenizer.bos_token_id
+ self.dataset = dataset
+ self.seq_length = seq_length
+ self.input_characters = seq_length * chars_per_token * num_of_sequences
+
+ def __iter__(self):
+ iterator = iter(self.dataset)
+ more_examples = True
+ while more_examples:
+ buffer, buffer_len = [], 0
+ while True:
+ if buffer_len >= self.input_characters:
+ break
+ try:
+ buffer.append(next(iterator)["content"])
+ buffer_len += len(buffer[-1])
+ except StopIteration:
+ more_examples = False
+ break
+ tokenized_inputs = tokenizer(buffer, truncation=False)["input_ids"]
+ all_token_ids = []
+ for tokenized_input in tokenized_inputs:
+ all_token_ids.extend(tokenized_input + [self.concat_token_id])
+ for i in range(0, len(all_token_ids), self.seq_length):
+ input_ids = all_token_ids[i : i + self.seq_length]
+ if len(input_ids) == self.seq_length:
+ yield torch.tensor(input_ids)
+
+
+def create_dataloader(args):
+ ds_kwargs = {"streaming": True}
+ valid_data = load_dataset(args.dataset_name, split="train", **ds_kwargs)
+ valid_dataset = ConstantLengthDataset(tokenizer, valid_data, seq_length=args.seq_length)
+ eval_dataloader = DataLoader(valid_dataset, batch_size=args.batch_size)
+ return eval_dataloader
+
+
+def evaluate(args):
+ model.eval()
+ losses = []
+ for step, batch in enumerate(eval_dataloader):
+ with torch.no_grad():
+ outputs = model(batch, labels=batch)
+ loss = outputs.loss.repeat(args.batch_size)
+ losses.append(accelerator.gather(loss))
+
+ if args.max_eval_steps > 0 and step >= args.max_eval_steps:
+ break
+ loss = torch.mean(torch.cat(losses))
+ try:
+ perplexity = torch.exp(loss)
+ except OverflowError:
+ perplexity = float("inf")
+ return loss.item(), perplexity.item()
+
+
+# Setup Accelerator
+accelerator = Accelerator()
+
+# Parse configuration
+parser = HfArgumentParser(EvaluationArguments)
+args = parser.parse_args()
+set_seed(args.seed)
+
+# Logging
+logger = logging.getLogger(__name__)
+logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s", datefmt="%m/%d/%Y %H:%M:%S", level=logging.INFO
+)
+
+# Load model and tokenizer
+model = AutoModelForCausalLM.from_pretrained(args.model_ckpt)
+tokenizer = AutoTokenizer.from_pretrained(args.model_ckpt)
+
+# Load dataset and dataloader
+eval_dataloader = create_dataloader(args)
+
+# Prepare everything with our `accelerator`.
+model, eval_dataloader = accelerator.prepare(model, eval_dataloader)
+
+# Evaluate and save the last checkpoint
+logger.info("Evaluating and saving model after training")
+eval_loss, perplexity = evaluate(args)
+logger.info(f"loss/eval: {eval_loss}, perplexity: {perplexity}")
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/decision_transformer/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/decision_transformer/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..b8ee442d9bfeaed6d02651c6541a94d103e591f0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/decision_transformer/requirements.txt
@@ -0,0 +1,240 @@
+absl-py==1.0.0
+aiohttp==3.10.11
+aiosignal==1.2.0
+alembic==1.7.7
+appdirs==1.4.4
+APScheduler==3.9.1
+arrow==1.2.2
+asttokens==2.0.5
+astunparse==1.6.3
+async-timeout==4.0.2
+attrs==21.4.0
+audioread==2.1.9
+autopage==0.5.0
+backcall==0.2.0
+backoff==1.11.1
+backports.zoneinfo==0.2.1
+binaryornot==0.4.4
+black==24.3.0
+boto3==1.16.34
+botocore==1.19.63
+Brotli==1.0.9
+cachetools==5.0.0
+certifi==2024.7.4
+cffi==1.15.0
+chardet==4.0.0
+charset-normalizer==2.0.12
+chex==0.1.1
+click==8.0.4
+cliff==3.10.1
+clldutils==3.11.1
+cloudpickle==2.0.0
+cmaes==0.8.2
+cmd2==2.4.0
+codecarbon==1.2.0
+colorlog==6.6.0
+cookiecutter==2.1.1
+cryptography==43.0.1
+csvw==2.0.0
+cycler==0.11.0
+Cython==0.29.28
+dash==2.15.0
+dash-bootstrap-components==1.0.3
+dash-core-components==2.0.0
+dash-html-components==2.0.0
+dash-table==5.0.0
+datasets==2.0.0
+decorator==5.1.1
+Deprecated==1.2.13
+dill==0.3.4
+dlinfo==1.2.1
+dm-tree==0.1.6
+docker==4.4.4
+execnet==1.9.0
+executing==0.8.3
+faiss-cpu==1.7.2
+fasteners==0.17.3
+filelock==3.6.0
+fire==0.4.0
+flake8==4.0.1
+Flask==2.3.2
+Flask-Compress==1.11
+flatbuffers==2.0
+flax==0.4.0
+fonttools==4.43.0
+frozenlist==1.3.0
+fsspec==2022.2.0
+fugashi==1.1.2
+gast==0.5.3
+gitdb==4.0.9
+GitPython==3.1.41
+glfw==2.5.1
+google-auth==2.6.2
+google-auth-oauthlib==0.4.6
+google-pasta==0.2.0
+greenlet==1.1.2
+grpcio==1.53.2
+gym==0.23.1
+gym-notices==0.0.6
+h5py==3.6.0
+huggingface-hub==0.4.0
+hypothesis==6.39.4
+idna==3.7
+imageio==2.16.1
+importlib-metadata==4.11.3
+importlib-resources==5.4.0
+iniconfig==1.1.1
+ipadic==1.0.0
+ipython==8.10.0
+isodate==0.6.1
+isort==5.10.1
+itsdangerous==2.1.1
+jax==0.3.4
+jaxlib==0.3.2
+jedi==0.18.1
+Jinja2==3.1.5
+jinja2-time==0.2.0
+jmespath==0.10.0
+joblib==1.2.0
+jsonschema==4.4.0
+keras==2.13.1
+Keras-Preprocessing==1.1.2
+kiwisolver==1.4.0
+kubernetes==12.0.1
+libclang==13.0.0
+librosa==0.9.1
+llvmlite==0.38.0
+Mako==1.2.2
+Markdown==3.3.6
+MarkupSafe==1.1.1
+matplotlib==3.5.1
+matplotlib-inline==0.1.3
+mccabe==0.6.1
+msgpack==1.0.3
+mujoco-py==2.1.2.14
+multidict==6.0.2
+multiprocess==0.70.12.2
+mypy-extensions==0.4.3
+nltk==3.9
+numba==0.55.1
+numpy==1.22.3
+oauthlib==3.2.2
+onnx>=1.15.0
+onnxconverter-common==1.9.0
+opt-einsum==3.3.0
+optax==0.1.1
+optuna==2.10.0
+packaging==21.3
+pandas==1.4.1
+parameterized==0.8.1
+parso==0.8.3
+pathspec==0.9.0
+pbr==5.8.1
+pexpect==4.8.0
+phonemizer==3.0.1
+pickleshare==0.7.5
+Pillow==10.3.0
+Pint==0.16.1
+plac==1.3.4
+platformdirs==2.5.1
+plotly==5.6.0
+pluggy==1.0.0
+pooch==1.6.0
+portalocker==2.0.0
+poyo==0.5.0
+prettytable==3.2.0
+prompt-toolkit==3.0.28
+protobuf==3.19.5
+psutil==5.9.0
+ptyprocess==0.7.0
+pure-eval==0.2.2
+py==1.11.0
+py-cpuinfo==8.0.0
+pyarrow==15.0.0
+pyasn1==0.4.8
+pyasn1-modules==0.2.8
+pycodestyle==2.8.0
+pycparser==2.21
+pyctcdecode==0.3.0
+pyflakes==2.4.0
+Pygments==2.15.0
+pygtrie==2.4.2
+pynvml==11.4.1
+pyOpenSSL==22.0.0
+pyparsing==3.0.7
+pyperclip==1.8.2
+pypng==0.0.21
+pyrsistent==0.18.1
+pytest==7.1.1
+pytest-forked==1.4.0
+pytest-timeout==2.1.0
+pytest-xdist==2.5.0
+python-dateutil==2.8.2
+python-slugify==6.1.1
+pytz==2022.1
+pytz-deprecation-shim==0.1.0.post0
+PyYAML==6.0
+ray>2.6.3
+redis==4.5.4
+regex==2022.3.15
+requests==2.32.0
+requests-oauthlib==1.3.1
+resampy==0.2.2
+responses==0.18.0
+rfc3986==1.5.0
+rouge-score==0.0.4
+rsa==4.8
+s3transfer==0.3.7
+sacrebleu==1.5.1
+sacremoses==0.0.49
+scikit-learn==1.5.0
+scipy==1.8.0
+segments==2.2.0
+sentencepiece==0.1.96
+sigopt==8.2.0
+six==1.16.0
+smmap==5.0.0
+sortedcontainers==2.4.0
+SoundFile==0.10.3.post1
+SQLAlchemy==1.4.32
+stack-data==0.2.0
+stevedore==3.5.0
+tabulate==0.8.9
+tenacity==8.0.1
+tensorboard==2.8.0
+tensorboard-data-server==0.6.1
+tensorboard-plugin-wit==1.8.1
+tensorboardX==2.5
+tensorflow==2.12.1
+tensorflow-io-gcs-filesystem==0.24.0
+termcolor==1.1.0
+text-unidecode==1.3
+tf-estimator-nightly==2.8.0.dev2021122109
+tf2onnx==1.9.3
+threadpoolctl==3.1.0
+timeout-decorator==0.5.0
+timm==0.5.4
+tokenizers==0.11.6
+tomli==2.0.1
+toolz==0.11.2
+torch==2.2.0
+torchaudio==0.11.0
+torchvision==0.12.0
+tqdm==4.66.3
+traitlets==5.1.1
+-e git+git@github.com:edbeeching/transformers.git@77b90113ca0a0e4058b046796c874bdc98f1da61#egg=transformers
+typing-extensions==4.1.1
+tzdata==2022.1
+tzlocal==4.1
+unidic==1.1.0
+unidic-lite==1.0.8
+uritemplate==4.1.1
+urllib3==1.26.19
+wasabi==0.9.0
+wcwidth==0.2.5
+websocket-client==1.3.1
+Werkzeug==3.0.6
+wrapt==1.14.0
+xxhash==3.0.0
+yarl==1.7.2
+zipp==3.19.1
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/decision_transformer/run_decision_transformer.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/decision_transformer/run_decision_transformer.py
new file mode 100644
index 0000000000000000000000000000000000000000..d6c3e28331259d01fa0f82c29f0dca593c908856
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/decision_transformer/run_decision_transformer.py
@@ -0,0 +1,173 @@
+import gym
+import numpy as np
+import torch
+from mujoco_py import GlfwContext
+
+from transformers import DecisionTransformerModel
+
+
+GlfwContext(offscreen=True) # Create a window to init GLFW.
+
+
+def get_action(model, states, actions, rewards, returns_to_go, timesteps):
+ # we don't care about the past rewards in this model
+
+ states = states.reshape(1, -1, model.config.state_dim)
+ actions = actions.reshape(1, -1, model.config.act_dim)
+ returns_to_go = returns_to_go.reshape(1, -1, 1)
+ timesteps = timesteps.reshape(1, -1)
+
+ if model.config.max_length is not None:
+ states = states[:, -model.config.max_length :]
+ actions = actions[:, -model.config.max_length :]
+ returns_to_go = returns_to_go[:, -model.config.max_length :]
+ timesteps = timesteps[:, -model.config.max_length :]
+
+ # pad all tokens to sequence length
+ attention_mask = torch.cat(
+ [torch.zeros(model.config.max_length - states.shape[1]), torch.ones(states.shape[1])]
+ )
+ attention_mask = attention_mask.to(dtype=torch.long, device=states.device).reshape(1, -1)
+ states = torch.cat(
+ [
+ torch.zeros(
+ (states.shape[0], model.config.max_length - states.shape[1], model.config.state_dim),
+ device=states.device,
+ ),
+ states,
+ ],
+ dim=1,
+ ).to(dtype=torch.float32)
+ actions = torch.cat(
+ [
+ torch.zeros(
+ (actions.shape[0], model.config.max_length - actions.shape[1], model.config.act_dim),
+ device=actions.device,
+ ),
+ actions,
+ ],
+ dim=1,
+ ).to(dtype=torch.float32)
+ returns_to_go = torch.cat(
+ [
+ torch.zeros(
+ (returns_to_go.shape[0], model.config.max_length - returns_to_go.shape[1], 1),
+ device=returns_to_go.device,
+ ),
+ returns_to_go,
+ ],
+ dim=1,
+ ).to(dtype=torch.float32)
+ timesteps = torch.cat(
+ [
+ torch.zeros(
+ (timesteps.shape[0], model.config.max_length - timesteps.shape[1]), device=timesteps.device
+ ),
+ timesteps,
+ ],
+ dim=1,
+ ).to(dtype=torch.long)
+ else:
+ attention_mask = None
+
+ _, action_preds, _ = model(
+ states=states,
+ actions=actions,
+ rewards=rewards,
+ returns_to_go=returns_to_go,
+ timesteps=timesteps,
+ attention_mask=attention_mask,
+ return_dict=False,
+ )
+
+ return action_preds[0, -1]
+
+
+# build the environment
+
+env = gym.make("Hopper-v3")
+state_dim = env.observation_space.shape[0]
+act_dim = env.action_space.shape[0]
+max_ep_len = 1000
+device = "cuda"
+scale = 1000.0 # normalization for rewards/returns
+TARGET_RETURN = 3600 / scale # evaluation conditioning targets, 3600 is reasonable from the paper LINK
+state_mean = np.array(
+ [
+ 1.311279,
+ -0.08469521,
+ -0.5382719,
+ -0.07201576,
+ 0.04932366,
+ 2.1066856,
+ -0.15017354,
+ 0.00878345,
+ -0.2848186,
+ -0.18540096,
+ -0.28461286,
+ ]
+)
+state_std = np.array(
+ [
+ 0.17790751,
+ 0.05444621,
+ 0.21297139,
+ 0.14530419,
+ 0.6124444,
+ 0.85174465,
+ 1.4515252,
+ 0.6751696,
+ 1.536239,
+ 1.6160746,
+ 5.6072536,
+ ]
+)
+state_mean = torch.from_numpy(state_mean).to(device=device)
+state_std = torch.from_numpy(state_std).to(device=device)
+
+# Create the decision transformer model
+model = DecisionTransformerModel.from_pretrained("edbeeching/decision-transformer-gym-hopper-medium")
+model = model.to(device)
+model.eval()
+
+for ep in range(10):
+ episode_return, episode_length = 0, 0
+ state = env.reset()
+ target_return = torch.tensor(TARGET_RETURN, device=device, dtype=torch.float32).reshape(1, 1)
+ states = torch.from_numpy(state).reshape(1, state_dim).to(device=device, dtype=torch.float32)
+ actions = torch.zeros((0, act_dim), device=device, dtype=torch.float32)
+ rewards = torch.zeros(0, device=device, dtype=torch.float32)
+
+ timesteps = torch.tensor(0, device=device, dtype=torch.long).reshape(1, 1)
+ for t in range(max_ep_len):
+ env.render()
+ # add padding
+ actions = torch.cat([actions, torch.zeros((1, act_dim), device=device)], dim=0)
+ rewards = torch.cat([rewards, torch.zeros(1, device=device)])
+
+ action = get_action(
+ model,
+ (states.to(dtype=torch.float32) - state_mean) / state_std,
+ actions.to(dtype=torch.float32),
+ rewards.to(dtype=torch.float32),
+ target_return.to(dtype=torch.float32),
+ timesteps.to(dtype=torch.long),
+ )
+ actions[-1] = action
+ action = action.detach().cpu().numpy()
+
+ state, reward, done, _ = env.step(action)
+
+ cur_state = torch.from_numpy(state).to(device=device).reshape(1, state_dim)
+ states = torch.cat([states, cur_state], dim=0)
+ rewards[-1] = reward
+
+ pred_return = target_return[0, -1] - (reward / scale)
+ target_return = torch.cat([target_return, pred_return.reshape(1, 1)], dim=1)
+ timesteps = torch.cat([timesteps, torch.ones((1, 1), device=device, dtype=torch.long) * (t + 1)], dim=1)
+
+ episode_return += reward
+ episode_length += 1
+
+ if done:
+ break
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..08a087dc03ebafec1e257c8e0b4982645d5ce01e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/README.md
@@ -0,0 +1,54 @@
+# DeeBERT: Early Exiting for *BERT
+
+This is the code base for the paper [DeeBERT: Dynamic Early Exiting for Accelerating BERT Inference](https://www.aclweb.org/anthology/2020.acl-main.204/), modified from its [original code base](https://github.com/castorini/deebert).
+
+The original code base also has information for downloading sample models that we have trained in advance.
+
+## Usage
+
+There are three scripts in the folder which can be run directly.
+
+In each script, there are several things to modify before running:
+
+* `PATH_TO_DATA`: path to the GLUE dataset.
+* `--output_dir`: path for saving fine-tuned models. Default: `./saved_models`.
+* `--plot_data_dir`: path for saving evaluation results. Default: `./results`. Results are printed to stdout and also saved to `npy` files in this directory to facilitate plotting figures and further analyses.
+* `MODEL_TYPE`: bert or roberta
+* `MODEL_SIZE`: base or large
+* `DATASET`: SST-2, MRPC, RTE, QNLI, QQP, or MNLI
+
+#### train_deebert.sh
+
+This is for fine-tuning DeeBERT models.
+
+#### eval_deebert.sh
+
+This is for evaluating each exit layer for fine-tuned DeeBERT models.
+
+#### entropy_eval.sh
+
+This is for evaluating fine-tuned DeeBERT models, given a number of different early exit entropy thresholds.
+
+
+
+## Citation
+
+Please cite our paper if you find the resource useful:
+```bibtex
+@inproceedings{xin-etal-2020-deebert,
+ title = "{D}ee{BERT}: Dynamic Early Exiting for Accelerating {BERT} Inference",
+ author = "Xin, Ji and
+ Tang, Raphael and
+ Lee, Jaejun and
+ Yu, Yaoliang and
+ Lin, Jimmy",
+ booktitle = "Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics",
+ month = jul,
+ year = "2020",
+ address = "Online",
+ publisher = "Association for Computational Linguistics",
+ url = "https://www.aclweb.org/anthology/2020.acl-main.204",
+ pages = "2246--2251",
+}
+```
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/entropy_eval.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/entropy_eval.sh
new file mode 100644
index 0000000000000000000000000000000000000000..884c286a56a598bf5f1e79debe258821b673ac46
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/entropy_eval.sh
@@ -0,0 +1,33 @@
+#!/bin/bash
+export CUDA_VISIBLE_DEVICES=0
+
+PATH_TO_DATA=/h/xinji/projects/GLUE
+
+MODEL_TYPE=bert # bert or roberta
+MODEL_SIZE=base # base or large
+DATASET=MRPC # SST-2, MRPC, RTE, QNLI, QQP, or MNLI
+
+MODEL_NAME=${MODEL_TYPE}-${MODEL_SIZE}
+if [ $MODEL_TYPE = 'bert' ]
+then
+ MODEL_NAME=${MODEL_NAME}-uncased
+fi
+
+ENTROPIES="0 0.1 0.2 0.3 0.4 0.5 0.6 0.7"
+
+for ENTROPY in $ENTROPIES; do
+ python -u run_glue_deebert.py \
+ --model_type $MODEL_TYPE \
+ --model_name_or_path ./saved_models/${MODEL_TYPE}-${MODEL_SIZE}/$DATASET/two_stage \
+ --task_name $DATASET \
+ --do_eval \
+ --do_lower_case \
+ --data_dir $PATH_TO_DATA/$DATASET \
+ --output_dir ./saved_models/${MODEL_TYPE}-${MODEL_SIZE}/$DATASET/two_stage \
+ --plot_data_dir ./results/ \
+ --max_seq_length 128 \
+ --early_exit_entropy $ENTROPY \
+ --eval_highway \
+ --overwrite_cache \
+ --per_gpu_eval_batch_size=1
+done
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/eval_deebert.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/eval_deebert.sh
new file mode 100644
index 0000000000000000000000000000000000000000..adf4f652a9f7135657c5f5e8400aa47a65d907e0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/eval_deebert.sh
@@ -0,0 +1,30 @@
+#!/bin/bash
+export CUDA_VISIBLE_DEVICES=0
+
+PATH_TO_DATA=/h/xinji/projects/GLUE
+
+MODEL_TYPE=bert # bert or roberta
+MODEL_SIZE=base # base or large
+DATASET=MRPC # SST-2, MRPC, RTE, QNLI, QQP, or MNLI
+
+MODEL_NAME=${MODEL_TYPE}-${MODEL_SIZE}
+if [ $MODEL_TYPE = 'bert' ]
+then
+ MODEL_NAME=${MODEL_NAME}-uncased
+fi
+
+
+python -u run_glue_deebert.py \
+ --model_type $MODEL_TYPE \
+ --model_name_or_path ./saved_models/${MODEL_TYPE}-${MODEL_SIZE}/$DATASET/two_stage \
+ --task_name $DATASET \
+ --do_eval \
+ --do_lower_case \
+ --data_dir $PATH_TO_DATA/$DATASET \
+ --output_dir ./saved_models/${MODEL_TYPE}-${MODEL_SIZE}/$DATASET/two_stage \
+ --plot_data_dir ./results/ \
+ --max_seq_length 128 \
+ --eval_each_highway \
+ --eval_highway \
+ --overwrite_cache \
+ --per_gpu_eval_batch_size=1
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..99636a7fce1b8ebdd049db2bdeb2248c02791fce
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/requirements.txt
@@ -0,0 +1 @@
+transformers == 4.38.0
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/run_glue_deebert.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/run_glue_deebert.py
new file mode 100644
index 0000000000000000000000000000000000000000..6ca28ab5bc07bc082b4f424a06713e437d4e3be8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/run_glue_deebert.py
@@ -0,0 +1,735 @@
+from __future__ import absolute_import, division, print_function
+
+import argparse
+import glob
+import logging
+import os
+import random
+import time
+
+import numpy as np
+import torch
+from torch import nn
+from torch.utils.data import DataLoader, RandomSampler, SequentialSampler, TensorDataset
+from torch.utils.data.distributed import DistributedSampler
+from tqdm import tqdm, trange
+
+import transformers
+from src.modeling_highway_bert import DeeBertForSequenceClassification
+from src.modeling_highway_roberta import DeeRobertaForSequenceClassification
+from transformers import (
+ WEIGHTS_NAME,
+ AdamW,
+ BertConfig,
+ BertTokenizer,
+ RobertaConfig,
+ RobertaTokenizer,
+ get_linear_schedule_with_warmup,
+)
+from transformers import glue_compute_metrics as compute_metrics
+from transformers import glue_convert_examples_to_features as convert_examples_to_features
+from transformers import glue_output_modes as output_modes
+from transformers import glue_processors as processors
+from transformers.trainer_utils import is_main_process
+
+
+try:
+ from torch.utils.tensorboard import SummaryWriter
+except ImportError:
+ from tensorboardX import SummaryWriter
+
+
+logger = logging.getLogger(__name__)
+
+
+MODEL_CLASSES = {
+ "bert": (BertConfig, DeeBertForSequenceClassification, BertTokenizer),
+ "roberta": (RobertaConfig, DeeRobertaForSequenceClassification, RobertaTokenizer),
+}
+
+
+def set_seed(args):
+ random.seed(args.seed)
+ np.random.seed(args.seed)
+ torch.manual_seed(args.seed)
+ if args.n_gpu > 0:
+ torch.cuda.manual_seed_all(args.seed)
+
+
+def get_wanted_result(result):
+ if "spearmanr" in result:
+ print_result = result["spearmanr"]
+ elif "f1" in result:
+ print_result = result["f1"]
+ elif "mcc" in result:
+ print_result = result["mcc"]
+ elif "acc" in result:
+ print_result = result["acc"]
+ else:
+ raise ValueError("Primary metric unclear in the results")
+ return print_result
+
+
+def train(args, train_dataset, model, tokenizer, train_highway=False):
+ """Train the model"""
+ if args.local_rank in [-1, 0]:
+ tb_writer = SummaryWriter()
+
+ args.train_batch_size = args.per_gpu_train_batch_size * max(1, args.n_gpu)
+ train_sampler = RandomSampler(train_dataset) if args.local_rank == -1 else DistributedSampler(train_dataset)
+ train_dataloader = DataLoader(train_dataset, sampler=train_sampler, batch_size=args.train_batch_size)
+
+ if args.max_steps > 0:
+ t_total = args.max_steps
+ args.num_train_epochs = args.max_steps // (len(train_dataloader) // args.gradient_accumulation_steps) + 1
+ else:
+ t_total = len(train_dataloader) // args.gradient_accumulation_steps * args.num_train_epochs
+
+ # Prepare optimizer and schedule (linear warmup and decay)
+ no_decay = ["bias", "LayerNorm.weight"]
+ if train_highway:
+ optimizer_grouped_parameters = [
+ {
+ "params": [
+ p
+ for n, p in model.named_parameters()
+ if ("highway" in n) and (not any(nd in n for nd in no_decay))
+ ],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [
+ p for n, p in model.named_parameters() if ("highway" in n) and (any(nd in n for nd in no_decay))
+ ],
+ "weight_decay": 0.0,
+ },
+ ]
+ else:
+ optimizer_grouped_parameters = [
+ {
+ "params": [
+ p
+ for n, p in model.named_parameters()
+ if ("highway" not in n) and (not any(nd in n for nd in no_decay))
+ ],
+ "weight_decay": args.weight_decay,
+ },
+ {
+ "params": [
+ p
+ for n, p in model.named_parameters()
+ if ("highway" not in n) and (any(nd in n for nd in no_decay))
+ ],
+ "weight_decay": 0.0,
+ },
+ ]
+ optimizer = AdamW(optimizer_grouped_parameters, lr=args.learning_rate, eps=args.adam_epsilon)
+ scheduler = get_linear_schedule_with_warmup(
+ optimizer, num_warmup_steps=args.warmup_steps, num_training_steps=t_total
+ )
+ if args.fp16:
+ try:
+ from apex import amp
+ except ImportError:
+ raise ImportError("Please install apex from https://www.github.com/nvidia/apex to use fp16 training.")
+ model, optimizer = amp.initialize(model, optimizer, opt_level=args.fp16_opt_level)
+
+ # multi-gpu training (should be after apex fp16 initialization)
+ if args.n_gpu > 1:
+ model = nn.DataParallel(model)
+
+ # Distributed training (should be after apex fp16 initialization)
+ if args.local_rank != -1:
+ model = nn.parallel.DistributedDataParallel(
+ model, device_ids=[args.local_rank], output_device=args.local_rank, find_unused_parameters=True
+ )
+
+ # Train!
+ logger.info("***** Running training *****")
+ logger.info(" Num examples = %d", len(train_dataset))
+ logger.info(" Num Epochs = %d", args.num_train_epochs)
+ logger.info(" Instantaneous batch size per GPU = %d", args.per_gpu_train_batch_size)
+ logger.info(
+ " Total train batch size (w. parallel, distributed & accumulation) = %d",
+ args.train_batch_size
+ * args.gradient_accumulation_steps
+ * (torch.distributed.get_world_size() if args.local_rank != -1 else 1),
+ )
+ logger.info(" Gradient Accumulation steps = %d", args.gradient_accumulation_steps)
+ logger.info(" Total optimization steps = %d", t_total)
+
+ global_step = 0
+ tr_loss, logging_loss = 0.0, 0.0
+ model.zero_grad()
+ train_iterator = trange(int(args.num_train_epochs), desc="Epoch", disable=args.local_rank not in [-1, 0])
+ set_seed(args) # Added here for reproducibility (even between python 2 and 3)
+ for _ in train_iterator:
+ epoch_iterator = tqdm(train_dataloader, desc="Iteration", disable=args.local_rank not in [-1, 0])
+ for step, batch in enumerate(epoch_iterator):
+ model.train()
+ batch = tuple(t.to(args.device) for t in batch)
+ inputs = {"input_ids": batch[0], "attention_mask": batch[1], "labels": batch[3]}
+ if args.model_type != "distilbert":
+ inputs["token_type_ids"] = (
+ batch[2] if args.model_type in ["bert", "xlnet"] else None
+ ) # XLM, DistilBERT and RoBERTa don't use segment_ids
+ inputs["train_highway"] = train_highway
+ outputs = model(**inputs)
+ loss = outputs[0] # model outputs are always tuple in transformers (see doc)
+
+ if args.n_gpu > 1:
+ loss = loss.mean() # mean() to average on multi-gpu parallel training
+ if args.gradient_accumulation_steps > 1:
+ loss = loss / args.gradient_accumulation_steps
+
+ if args.fp16:
+ with amp.scale_loss(loss, optimizer) as scaled_loss:
+ scaled_loss.backward()
+ else:
+ loss.backward()
+
+ tr_loss += loss.item()
+ if (step + 1) % args.gradient_accumulation_steps == 0:
+ if args.fp16:
+ nn.utils.clip_grad_norm_(amp.master_params(optimizer), args.max_grad_norm)
+ else:
+ nn.utils.clip_grad_norm_(model.parameters(), args.max_grad_norm)
+
+ optimizer.step()
+ scheduler.step() # Update learning rate schedule
+ model.zero_grad()
+ global_step += 1
+
+ if args.local_rank in [-1, 0] and args.logging_steps > 0 and global_step % args.logging_steps == 0:
+ # Log metrics
+ if (
+ args.local_rank == -1 and args.evaluate_during_training
+ ): # Only evaluate when single GPU otherwise metrics may not average well
+ results = evaluate(args, model, tokenizer)
+ for key, value in results.items():
+ tb_writer.add_scalar("eval_{}".format(key), value, global_step)
+ tb_writer.add_scalar("lr", scheduler.get_lr()[0], global_step)
+ tb_writer.add_scalar("loss", (tr_loss - logging_loss) / args.logging_steps, global_step)
+ logging_loss = tr_loss
+
+ if args.local_rank in [-1, 0] and args.save_steps > 0 and global_step % args.save_steps == 0:
+ # Save model checkpoint
+ output_dir = os.path.join(args.output_dir, "checkpoint-{}".format(global_step))
+ if not os.path.exists(output_dir):
+ os.makedirs(output_dir)
+ model_to_save = (
+ model.module if hasattr(model, "module") else model
+ ) # Take care of distributed/parallel training
+ model_to_save.save_pretrained(output_dir)
+ torch.save(args, os.path.join(output_dir, "training_args.bin"))
+ logger.info("Saving model checkpoint to %s", output_dir)
+
+ if args.max_steps > 0 and global_step > args.max_steps:
+ epoch_iterator.close()
+ break
+ if args.max_steps > 0 and global_step > args.max_steps:
+ train_iterator.close()
+ break
+
+ if args.local_rank in [-1, 0]:
+ tb_writer.close()
+
+ return global_step, tr_loss / global_step
+
+
+def evaluate(args, model, tokenizer, prefix="", output_layer=-1, eval_highway=False):
+ # Loop to handle MNLI double evaluation (matched, mis-matched)
+ eval_task_names = ("mnli", "mnli-mm") if args.task_name == "mnli" else (args.task_name,)
+ eval_outputs_dirs = (args.output_dir, args.output_dir + "-MM") if args.task_name == "mnli" else (args.output_dir,)
+
+ results = {}
+ for eval_task, eval_output_dir in zip(eval_task_names, eval_outputs_dirs):
+ eval_dataset = load_and_cache_examples(args, eval_task, tokenizer, evaluate=True)
+
+ if not os.path.exists(eval_output_dir) and args.local_rank in [-1, 0]:
+ os.makedirs(eval_output_dir)
+
+ args.eval_batch_size = args.per_gpu_eval_batch_size * max(1, args.n_gpu)
+ # Note that DistributedSampler samples randomly
+ eval_sampler = SequentialSampler(eval_dataset) if args.local_rank == -1 else DistributedSampler(eval_dataset)
+ eval_dataloader = DataLoader(eval_dataset, sampler=eval_sampler, batch_size=args.eval_batch_size)
+
+ # multi-gpu eval
+ if args.n_gpu > 1:
+ model = nn.DataParallel(model)
+
+ # Eval!
+ logger.info("***** Running evaluation {} *****".format(prefix))
+ logger.info(" Num examples = %d", len(eval_dataset))
+ logger.info(" Batch size = %d", args.eval_batch_size)
+ eval_loss = 0.0
+ nb_eval_steps = 0
+ preds = None
+ out_label_ids = None
+ exit_layer_counter = {(i + 1): 0 for i in range(model.num_layers)}
+ st = time.time()
+ for batch in tqdm(eval_dataloader, desc="Evaluating"):
+ model.eval()
+ batch = tuple(t.to(args.device) for t in batch)
+
+ with torch.no_grad():
+ inputs = {"input_ids": batch[0], "attention_mask": batch[1], "labels": batch[3]}
+ if args.model_type != "distilbert":
+ inputs["token_type_ids"] = (
+ batch[2] if args.model_type in ["bert", "xlnet"] else None
+ ) # XLM, DistilBERT and RoBERTa don't use segment_ids
+ if output_layer >= 0:
+ inputs["output_layer"] = output_layer
+ outputs = model(**inputs)
+ if eval_highway:
+ exit_layer_counter[outputs[-1]] += 1
+ tmp_eval_loss, logits = outputs[:2]
+
+ eval_loss += tmp_eval_loss.mean().item()
+ nb_eval_steps += 1
+ if preds is None:
+ preds = logits.detach().cpu().numpy()
+ out_label_ids = inputs["labels"].detach().cpu().numpy()
+ else:
+ preds = np.append(preds, logits.detach().cpu().numpy(), axis=0)
+ out_label_ids = np.append(out_label_ids, inputs["labels"].detach().cpu().numpy(), axis=0)
+ eval_time = time.time() - st
+ logger.info("Eval time: {}".format(eval_time))
+
+ eval_loss = eval_loss / nb_eval_steps
+ if args.output_mode == "classification":
+ preds = np.argmax(preds, axis=1)
+ elif args.output_mode == "regression":
+ preds = np.squeeze(preds)
+ result = compute_metrics(eval_task, preds, out_label_ids)
+ results.update(result)
+
+ if eval_highway:
+ logger.info("Exit layer counter: {}".format(exit_layer_counter))
+ actual_cost = sum([l * c for l, c in exit_layer_counter.items()])
+ full_cost = len(eval_dataloader) * model.num_layers
+ logger.info("Expected saving: {}".format(actual_cost / full_cost))
+ if args.early_exit_entropy >= 0:
+ save_fname = (
+ args.plot_data_dir
+ + "/"
+ + args.model_name_or_path[2:]
+ + "/entropy_{}.npy".format(args.early_exit_entropy)
+ )
+ if not os.path.exists(os.path.dirname(save_fname)):
+ os.makedirs(os.path.dirname(save_fname))
+ print_result = get_wanted_result(result)
+ np.save(save_fname, np.array([exit_layer_counter, eval_time, actual_cost / full_cost, print_result]))
+ logger.info("Entropy={}\tResult={:.2f}".format(args.early_exit_entropy, 100 * print_result))
+
+ output_eval_file = os.path.join(eval_output_dir, prefix, "eval_results.txt")
+ with open(output_eval_file, "w") as writer:
+ logger.info("***** Eval results {} *****".format(prefix))
+ for key in sorted(result.keys()):
+ logger.info(" %s = %s", key, str(result[key]))
+ writer.write("%s = %s\n" % (key, str(result[key])))
+
+ return results
+
+
+def load_and_cache_examples(args, task, tokenizer, evaluate=False):
+ if args.local_rank not in [-1, 0] and not evaluate:
+ torch.distributed.barrier() # Make sure only the first process in distributed training process the dataset, and the others will use the cache
+
+ processor = processors[task]()
+ output_mode = output_modes[task]
+ # Load data features from cache or dataset file
+ cached_features_file = os.path.join(
+ args.data_dir,
+ "cached_{}_{}_{}_{}".format(
+ "dev" if evaluate else "train",
+ list(filter(None, args.model_name_or_path.split("/"))).pop(),
+ str(args.max_seq_length),
+ str(task),
+ ),
+ )
+ if os.path.exists(cached_features_file) and not args.overwrite_cache:
+ logger.info("Loading features from cached file %s", cached_features_file)
+ features = torch.load(cached_features_file)
+ else:
+ logger.info("Creating features from dataset file at %s", args.data_dir)
+ label_list = processor.get_labels()
+ if task in ["mnli", "mnli-mm"] and args.model_type in ["roberta"]:
+ # HACK(label indices are swapped in RoBERTa pretrained model)
+ label_list[1], label_list[2] = label_list[2], label_list[1]
+ examples = (
+ processor.get_dev_examples(args.data_dir) if evaluate else processor.get_train_examples(args.data_dir)
+ )
+ features = convert_examples_to_features(
+ examples,
+ tokenizer,
+ label_list=label_list,
+ max_length=args.max_seq_length,
+ output_mode=output_mode,
+ )
+ if args.local_rank in [-1, 0]:
+ logger.info("Saving features into cached file %s", cached_features_file)
+ torch.save(features, cached_features_file)
+
+ if args.local_rank == 0 and not evaluate:
+ torch.distributed.barrier() # Make sure only the first process in distributed training process the dataset, and the others will use the cache
+
+ # Convert to Tensors and build dataset
+ all_input_ids = torch.tensor([f.input_ids for f in features], dtype=torch.long)
+ all_attention_mask = torch.tensor([f.attention_mask for f in features], dtype=torch.long)
+
+ if features[0].token_type_ids is None:
+ # For RoBERTa (a potential bug!)
+ all_token_type_ids = torch.tensor([[0] * args.max_seq_length for f in features], dtype=torch.long)
+ else:
+ all_token_type_ids = torch.tensor([f.token_type_ids for f in features], dtype=torch.long)
+ if output_mode == "classification":
+ all_labels = torch.tensor([f.label for f in features], dtype=torch.long)
+ elif output_mode == "regression":
+ all_labels = torch.tensor([f.label for f in features], dtype=torch.float)
+
+ dataset = TensorDataset(all_input_ids, all_attention_mask, all_token_type_ids, all_labels)
+ return dataset
+
+
+def main():
+ parser = argparse.ArgumentParser()
+
+ # Required parameters
+ parser.add_argument(
+ "--data_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The input data dir. Should contain the .tsv files (or other data files) for the task.",
+ )
+ parser.add_argument(
+ "--model_type",
+ default=None,
+ type=str,
+ required=True,
+ help="Model type selected in the list: " + ", ".join(MODEL_CLASSES.keys()),
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ default=None,
+ type=str,
+ required=True,
+ help="Path to pre-trained model or shortcut name.",
+ )
+ parser.add_argument(
+ "--task_name",
+ default=None,
+ type=str,
+ required=True,
+ help="The name of the task to train selected in the list: " + ", ".join(processors.keys()),
+ )
+ parser.add_argument(
+ "--output_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The output directory where the model predictions and checkpoints will be written.",
+ )
+ parser.add_argument(
+ "--plot_data_dir",
+ default="./plotting/",
+ type=str,
+ required=False,
+ help="The directory to store data for plotting figures.",
+ )
+
+ # Other parameters
+ parser.add_argument(
+ "--config_name", default="", type=str, help="Pretrained config name or path if not the same as model_name"
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ default="",
+ type=str,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--cache_dir",
+ default="",
+ type=str,
+ help="Where do you want to store the pre-trained models downloaded from huggingface.co",
+ )
+ parser.add_argument(
+ "--max_seq_length",
+ default=128,
+ type=int,
+ help=(
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ ),
+ )
+ parser.add_argument("--do_train", action="store_true", help="Whether to run training.")
+ parser.add_argument("--do_eval", action="store_true", help="Whether to run eval on the dev set.")
+ parser.add_argument(
+ "--evaluate_during_training", action="store_true", help="Rul evaluation during training at each logging step."
+ )
+ parser.add_argument(
+ "--do_lower_case", action="store_true", help="Set this flag if you are using an uncased model."
+ )
+ parser.add_argument("--eval_each_highway", action="store_true", help="Set this flag to evaluate each highway.")
+ parser.add_argument(
+ "--eval_after_first_stage",
+ action="store_true",
+ help="Set this flag to evaluate after training only bert (not highway).",
+ )
+ parser.add_argument("--eval_highway", action="store_true", help="Set this flag if it's evaluating highway models")
+
+ parser.add_argument("--per_gpu_train_batch_size", default=8, type=int, help="Batch size per GPU/CPU for training.")
+ parser.add_argument(
+ "--per_gpu_eval_batch_size", default=8, type=int, help="Batch size per GPU/CPU for evaluation."
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument("--learning_rate", default=5e-5, type=float, help="The initial learning rate for Adam.")
+ parser.add_argument("--weight_decay", default=0.0, type=float, help="Weight decay if we apply some.")
+ parser.add_argument("--adam_epsilon", default=1e-8, type=float, help="Epsilon for Adam optimizer.")
+ parser.add_argument("--max_grad_norm", default=1.0, type=float, help="Max gradient norm.")
+ parser.add_argument(
+ "--num_train_epochs", default=3.0, type=float, help="Total number of training epochs to perform."
+ )
+ parser.add_argument(
+ "--max_steps",
+ default=-1,
+ type=int,
+ help="If > 0: set total number of training steps to perform. Override num_train_epochs.",
+ )
+ parser.add_argument("--warmup_steps", default=0, type=int, help="Linear warmup over warmup_steps.")
+ parser.add_argument("--early_exit_entropy", default=-1, type=float, help="Entropy threshold for early exit.")
+
+ parser.add_argument("--logging_steps", type=int, default=50, help="Log every X updates steps.")
+ parser.add_argument("--save_steps", type=int, default=50, help="Save checkpoint every X updates steps.")
+ parser.add_argument(
+ "--eval_all_checkpoints",
+ action="store_true",
+ help="Evaluate all checkpoints starting with the same prefix as model_name ending and ending with step number",
+ )
+ parser.add_argument("--no_cuda", action="store_true", help="Avoid using CUDA when available")
+ parser.add_argument(
+ "--overwrite_output_dir", action="store_true", help="Overwrite the content of the output directory"
+ )
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+ parser.add_argument("--seed", type=int, default=42, help="random seed for initialization")
+
+ parser.add_argument(
+ "--fp16",
+ action="store_true",
+ help="Whether to use 16-bit (mixed) precision (through NVIDIA apex) instead of 32-bit",
+ )
+ parser.add_argument(
+ "--fp16_opt_level",
+ type=str,
+ default="O1",
+ help=(
+ "For fp16: Apex AMP optimization level selected in ['O0', 'O1', 'O2', and 'O3']. "
+ "See details at https://nvidia.github.io/apex/amp.html"
+ ),
+ )
+ parser.add_argument("--local_rank", type=int, default=-1, help="For distributed training: local_rank")
+ parser.add_argument("--server_ip", type=str, default="", help="For distant debugging.")
+ parser.add_argument("--server_port", type=str, default="", help="For distant debugging.")
+ args = parser.parse_args()
+
+ if (
+ os.path.exists(args.output_dir)
+ and os.listdir(args.output_dir)
+ and args.do_train
+ and not args.overwrite_output_dir
+ ):
+ raise ValueError(
+ "Output directory ({}) already exists and is not empty. Use --overwrite_output_dir to overcome.".format(
+ args.output_dir
+ )
+ )
+
+ # Setup distant debugging if needed
+ if args.server_ip and args.server_port:
+ # Distant debugging - see https://code.visualstudio.com/docs/python/debugging#_attach-to-a-local-script
+ import ptvsd
+
+ print("Waiting for debugger attach")
+ ptvsd.enable_attach(address=(args.server_ip, args.server_port), redirect_output=True)
+ ptvsd.wait_for_attach()
+
+ # Setup CUDA, GPU & distributed training
+ if args.local_rank == -1 or args.no_cuda:
+ device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
+ args.n_gpu = torch.cuda.device_count()
+ else: # Initializes the distributed backend which will take care of synchronizing nodes/GPUs
+ torch.cuda.set_device(args.local_rank)
+ device = torch.device("cuda", args.local_rank)
+ torch.distributed.init_process_group(backend="nccl")
+ args.n_gpu = 1
+ args.device = device
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO if args.local_rank in [-1, 0] else logging.WARN,
+ )
+ logger.warning(
+ "Process rank: %s, device: %s, n_gpu: %s, distributed training: %s, 16-bits training: %s",
+ args.local_rank,
+ device,
+ args.n_gpu,
+ bool(args.local_rank != -1),
+ args.fp16,
+ )
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ if is_main_process(args.local_rank):
+ transformers.utils.logging.set_verbosity_info()
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+ # Set seed
+ set_seed(args)
+
+ # Prepare GLUE task
+ args.task_name = args.task_name.lower()
+ if args.task_name not in processors:
+ raise ValueError("Task not found: %s" % (args.task_name))
+ processor = processors[args.task_name]()
+ args.output_mode = output_modes[args.task_name]
+ label_list = processor.get_labels()
+ num_labels = len(label_list)
+
+ # Load pretrained model and tokenizer
+ if args.local_rank not in [-1, 0]:
+ torch.distributed.barrier() # Make sure only the first process in distributed training will download model & vocab
+
+ args.model_type = args.model_type.lower()
+ config_class, model_class, tokenizer_class = MODEL_CLASSES[args.model_type]
+ config = config_class.from_pretrained(
+ args.config_name if args.config_name else args.model_name_or_path,
+ num_labels=num_labels,
+ finetuning_task=args.task_name,
+ cache_dir=args.cache_dir if args.cache_dir else None,
+ )
+ tokenizer = tokenizer_class.from_pretrained(
+ args.tokenizer_name if args.tokenizer_name else args.model_name_or_path,
+ do_lower_case=args.do_lower_case,
+ cache_dir=args.cache_dir if args.cache_dir else None,
+ )
+ model = model_class.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ cache_dir=args.cache_dir if args.cache_dir else None,
+ )
+
+ if args.model_type == "bert":
+ model.bert.encoder.set_early_exit_entropy(args.early_exit_entropy)
+ model.bert.init_highway_pooler()
+ elif args.model_type == "roberta":
+ model.roberta.encoder.set_early_exit_entropy(args.early_exit_entropy)
+ model.roberta.init_highway_pooler()
+ else:
+ raise NotImplementedError()
+
+ if args.local_rank == 0:
+ torch.distributed.barrier() # Make sure only the first process in distributed training will download model & vocab
+
+ model.to(args.device)
+
+ logger.info("Training/evaluation parameters %s", args)
+
+ # Training
+ if args.do_train:
+ train_dataset = load_and_cache_examples(args, args.task_name, tokenizer, evaluate=False)
+ global_step, tr_loss = train(args, train_dataset, model, tokenizer)
+ logger.info(" global_step = %s, average loss = %s", global_step, tr_loss)
+
+ if args.eval_after_first_stage:
+ result = evaluate(args, model, tokenizer, prefix="")
+ print_result = get_wanted_result(result)
+
+ train(args, train_dataset, model, tokenizer, train_highway=True)
+
+ # Saving best-practices: if you use defaults names for the model, you can reload it using from_pretrained()
+ if args.do_train and (args.local_rank == -1 or torch.distributed.get_rank() == 0):
+ # Create output directory if needed
+ if not os.path.exists(args.output_dir) and args.local_rank in [-1, 0]:
+ os.makedirs(args.output_dir)
+
+ logger.info("Saving model checkpoint to %s", args.output_dir)
+ # Save a trained model, configuration and tokenizer using `save_pretrained()`.
+ # They can then be reloaded using `from_pretrained()`
+ model_to_save = (
+ model.module if hasattr(model, "module") else model
+ ) # Take care of distributed/parallel training
+ model_to_save.save_pretrained(args.output_dir)
+ tokenizer.save_pretrained(args.output_dir)
+
+ # Good practice: save your training arguments together with the trained model
+ torch.save(args, os.path.join(args.output_dir, "training_args.bin"))
+
+ # Load a trained model and vocabulary that you have fine-tuned
+ model = model_class.from_pretrained(args.output_dir)
+ tokenizer = tokenizer_class.from_pretrained(args.output_dir)
+ model.to(args.device)
+
+ # Evaluation
+ results = {}
+ if args.do_eval and args.local_rank in [-1, 0]:
+ tokenizer = tokenizer_class.from_pretrained(args.output_dir, do_lower_case=args.do_lower_case)
+ checkpoints = [args.output_dir]
+ if args.eval_all_checkpoints:
+ checkpoints = [
+ os.path.dirname(c) for c in sorted(glob.glob(args.output_dir + "/**/" + WEIGHTS_NAME, recursive=True))
+ ]
+
+ logger.info("Evaluate the following checkpoints: %s", checkpoints)
+ for checkpoint in checkpoints:
+ global_step = checkpoint.split("-")[-1] if len(checkpoints) > 1 else ""
+ prefix = checkpoint.split("/")[-1] if checkpoint.find("checkpoint") != -1 else ""
+
+ model = model_class.from_pretrained(checkpoint)
+ if args.model_type == "bert":
+ model.bert.encoder.set_early_exit_entropy(args.early_exit_entropy)
+ elif args.model_type == "roberta":
+ model.roberta.encoder.set_early_exit_entropy(args.early_exit_entropy)
+ else:
+ raise NotImplementedError()
+
+ model.to(args.device)
+ result = evaluate(args, model, tokenizer, prefix=prefix, eval_highway=args.eval_highway)
+ print_result = get_wanted_result(result)
+ logger.info("Result: {}".format(print_result))
+ if args.eval_each_highway:
+ last_layer_results = print_result
+ each_layer_results = []
+ for i in range(model.num_layers):
+ logger.info("\n")
+ _result = evaluate(
+ args, model, tokenizer, prefix=prefix, output_layer=i, eval_highway=args.eval_highway
+ )
+ if i + 1 < model.num_layers:
+ each_layer_results.append(get_wanted_result(_result))
+ each_layer_results.append(last_layer_results)
+ save_fname = args.plot_data_dir + "/" + args.model_name_or_path[2:] + "/each_layer.npy"
+ if not os.path.exists(os.path.dirname(save_fname)):
+ os.makedirs(os.path.dirname(save_fname))
+ np.save(save_fname, np.array(each_layer_results))
+ info_str = "Score of each layer:"
+ for i in range(model.num_layers):
+ info_str += " {:.2f}".format(100 * each_layer_results[i])
+ logger.info(info_str)
+ result = {k + "_{}".format(global_step): v for k, v in result.items()}
+ results.update(result)
+
+ return results
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/src/__init__.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/src/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/src/modeling_highway_bert.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/src/modeling_highway_bert.py
new file mode 100644
index 0000000000000000000000000000000000000000..b866ef0869c7586abb7ff5173f0f0bb8b63034a1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/src/modeling_highway_bert.py
@@ -0,0 +1,397 @@
+import torch
+from torch import nn
+from torch.nn import CrossEntropyLoss, MSELoss
+
+from transformers.file_utils import add_start_docstrings, add_start_docstrings_to_model_forward
+from transformers.models.bert.modeling_bert import (
+ BERT_INPUTS_DOCSTRING,
+ BERT_START_DOCSTRING,
+ BertEmbeddings,
+ BertLayer,
+ BertPooler,
+ BertPreTrainedModel,
+)
+
+
+def entropy(x):
+ """Calculate entropy of a pre-softmax logit Tensor"""
+ exp_x = torch.exp(x)
+ A = torch.sum(exp_x, dim=1) # sum of exp(x_i)
+ B = torch.sum(x * exp_x, dim=1) # sum of x_i * exp(x_i)
+ return torch.log(A) - B / A
+
+
+class DeeBertEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.output_attentions = config.output_attentions
+ self.output_hidden_states = config.output_hidden_states
+ self.layer = nn.ModuleList([BertLayer(config) for _ in range(config.num_hidden_layers)])
+ self.highway = nn.ModuleList([BertHighway(config) for _ in range(config.num_hidden_layers)])
+
+ self.early_exit_entropy = [-1 for _ in range(config.num_hidden_layers)]
+
+ def set_early_exit_entropy(self, x):
+ if isinstance(x, (float, int)):
+ for i in range(len(self.early_exit_entropy)):
+ self.early_exit_entropy[i] = x
+ else:
+ self.early_exit_entropy = x
+
+ def init_highway_pooler(self, pooler):
+ loaded_model = pooler.state_dict()
+ for highway in self.highway:
+ for name, param in highway.pooler.state_dict().items():
+ param.copy_(loaded_model[name])
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ ):
+ all_hidden_states = ()
+ all_attentions = ()
+ all_highway_exits = ()
+ for i, layer_module in enumerate(self.layer):
+ if self.output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_outputs = layer_module(
+ hidden_states, attention_mask, head_mask[i], encoder_hidden_states, encoder_attention_mask
+ )
+ hidden_states = layer_outputs[0]
+
+ if self.output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ current_outputs = (hidden_states,)
+ if self.output_hidden_states:
+ current_outputs = current_outputs + (all_hidden_states,)
+ if self.output_attentions:
+ current_outputs = current_outputs + (all_attentions,)
+
+ highway_exit = self.highway[i](current_outputs)
+ # logits, pooled_output
+
+ if not self.training:
+ highway_logits = highway_exit[0]
+ highway_entropy = entropy(highway_logits)
+ highway_exit = highway_exit + (highway_entropy,) # logits, hidden_states(?), entropy
+ all_highway_exits = all_highway_exits + (highway_exit,)
+
+ if highway_entropy < self.early_exit_entropy[i]:
+ new_output = (highway_logits,) + current_outputs[1:] + (all_highway_exits,)
+ raise HighwayException(new_output, i + 1)
+ else:
+ all_highway_exits = all_highway_exits + (highway_exit,)
+
+ # Add last layer
+ if self.output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ outputs = (hidden_states,)
+ if self.output_hidden_states:
+ outputs = outputs + (all_hidden_states,)
+ if self.output_attentions:
+ outputs = outputs + (all_attentions,)
+
+ outputs = outputs + (all_highway_exits,)
+ return outputs # last-layer hidden state, (all hidden states), (all attentions), all highway exits
+
+
+@add_start_docstrings(
+ "The Bert Model transformer with early exiting (DeeBERT). ",
+ BERT_START_DOCSTRING,
+)
+class DeeBertModel(BertPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = BertEmbeddings(config)
+ self.encoder = DeeBertEncoder(config)
+ self.pooler = BertPooler(config)
+
+ self.init_weights()
+
+ def init_highway_pooler(self):
+ self.encoder.init_highway_pooler(self.pooler)
+
+ def get_input_embeddings(self):
+ return self.embeddings.word_embeddings
+
+ def set_input_embeddings(self, value):
+ self.embeddings.word_embeddings = value
+
+ def _prune_heads(self, heads_to_prune):
+ """Prunes heads of the model.
+ heads_to_prune: dict of {layer_num: list of heads to prune in this layer}
+ See base class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @add_start_docstrings_to_model_forward(BERT_INPUTS_DOCSTRING)
+ def forward(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ token_type_ids=None,
+ position_ids=None,
+ head_mask=None,
+ inputs_embeds=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ ):
+ r"""
+ Return:
+ :obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.BertConfig`) and inputs:
+ last_hidden_state (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`):
+ Sequence of hidden-states at the output of the last layer of the model.
+ pooler_output (:obj:`torch.FloatTensor`: of shape :obj:`(batch_size, hidden_size)`):
+ Last layer hidden-state of the first token of the sequence (classification token)
+ further processed by a Linear layer and a Tanh activation function. The Linear
+ layer weights are trained from the next sentence prediction (classification)
+ objective during pre-training.
+
+ This output is usually *not* a good summary
+ of the semantic content of the input, you're often better with averaging or pooling
+ the sequence of hidden-states for the whole input sequence.
+ hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_hidden_states=True`` is passed or when ``config.output_hidden_states=True``):
+ Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
+ of shape :obj:`(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
+ Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape
+ :obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ highway_exits (:obj:`tuple(tuple(torch.Tensor))`:
+ Tuple of each early exit's results (total length: number of layers)
+ Each tuple is again, a tuple of length 2 - the first entry is logits and the second entry is hidden states.
+ """
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ input_shape = input_ids.size()
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ if attention_mask is None:
+ attention_mask = torch.ones(input_shape, device=device)
+ if encoder_attention_mask is None:
+ encoder_attention_mask = torch.ones(input_shape, device=device)
+ if token_type_ids is None:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=device)
+
+ # We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length]
+ # ourselves in which case we just need to make it broadcastable to all heads.
+ extended_attention_mask: torch.Tensor = self.get_extended_attention_mask(attention_mask, input_shape, device)
+
+ # If a 2D ou 3D attention mask is provided for the cross-attention
+ # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length]
+ if encoder_attention_mask.dim() == 3:
+ encoder_extended_attention_mask = encoder_attention_mask[:, None, :, :]
+ if encoder_attention_mask.dim() == 2:
+ encoder_extended_attention_mask = encoder_attention_mask[:, None, None, :]
+
+ encoder_extended_attention_mask = encoder_extended_attention_mask.to(
+ dtype=next(self.parameters()).dtype
+ ) # fp16 compatibility
+ encoder_extended_attention_mask = (1.0 - encoder_extended_attention_mask) * -10000.0
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output = self.embeddings(
+ input_ids=input_ids, position_ids=position_ids, token_type_ids=token_type_ids, inputs_embeds=inputs_embeds
+ )
+ encoder_outputs = self.encoder(
+ embedding_output,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_extended_attention_mask,
+ )
+ sequence_output = encoder_outputs[0]
+ pooled_output = self.pooler(sequence_output)
+
+ outputs = (
+ sequence_output,
+ pooled_output,
+ ) + encoder_outputs[1:] # add hidden_states and attentions if they are here
+ return outputs # sequence_output, pooled_output, (hidden_states), (attentions), highway exits
+
+
+class HighwayException(Exception):
+ def __init__(self, message, exit_layer):
+ self.message = message
+ self.exit_layer = exit_layer # start from 1!
+
+
+class BertHighway(nn.Module):
+ """A module to provide a shortcut
+ from (the output of one non-final BertLayer in BertEncoder) to (cross-entropy computation in BertForSequenceClassification)
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ self.pooler = BertPooler(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+
+ def forward(self, encoder_outputs):
+ # Pooler
+ pooler_input = encoder_outputs[0]
+ pooler_output = self.pooler(pooler_input)
+ # "return" pooler_output
+
+ # BertModel
+ bmodel_output = (pooler_input, pooler_output) + encoder_outputs[1:]
+ # "return" bmodel_output
+
+ # Dropout and classification
+ pooled_output = bmodel_output[1]
+
+ pooled_output = self.dropout(pooled_output)
+ logits = self.classifier(pooled_output)
+
+ return logits, pooled_output
+
+
+@add_start_docstrings(
+ """Bert Model (with early exiting - DeeBERT) with a classifier on top,
+ also takes care of multi-layer training. """,
+ BERT_START_DOCSTRING,
+)
+class DeeBertForSequenceClassification(BertPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+ self.num_layers = config.num_hidden_layers
+
+ self.bert = DeeBertModel(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.classifier = nn.Linear(config.hidden_size, self.config.num_labels)
+
+ self.init_weights()
+
+ @add_start_docstrings_to_model_forward(BERT_INPUTS_DOCSTRING)
+ def forward(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ token_type_ids=None,
+ position_ids=None,
+ head_mask=None,
+ inputs_embeds=None,
+ labels=None,
+ output_layer=-1,
+ train_highway=False,
+ ):
+ r"""
+ labels (:obj:`torch.LongTensor` of shape :obj:`(batch_size,)`, `optional`):
+ Labels for computing the sequence classification/regression loss.
+ Indices should be in :obj:`[0, ..., config.num_labels - 1]`.
+ If :obj:`config.num_labels == 1` a regression loss is computed (Mean-Square loss),
+ If :obj:`config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+
+ Returns:
+ :obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.BertConfig`) and inputs:
+ loss (:obj:`torch.FloatTensor` of shape :obj:`(1,)`, `optional`, returned when :obj:`label` is provided):
+ Classification (or regression if config.num_labels==1) loss.
+ logits (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, config.num_labels)`):
+ Classification (or regression if config.num_labels==1) scores (before SoftMax).
+ hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_hidden_states=True`` is passed or when ``config.output_hidden_states=True``):
+ Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
+ of shape :obj:`(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
+ Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape
+ :obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ highway_exits (:obj:`tuple(tuple(torch.Tensor))`:
+ Tuple of each early exit's results (total length: number of layers)
+ Each tuple is again, a tuple of length 2 - the first entry is logits and the second entry is hidden states.
+ """
+
+ exit_layer = self.num_layers
+ try:
+ outputs = self.bert(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ )
+ # sequence_output, pooled_output, (hidden_states), (attentions), highway exits
+
+ pooled_output = outputs[1]
+
+ pooled_output = self.dropout(pooled_output)
+ logits = self.classifier(pooled_output)
+ outputs = (logits,) + outputs[2:] # add hidden states and attention if they are here
+ except HighwayException as e:
+ outputs = e.message
+ exit_layer = e.exit_layer
+ logits = outputs[0]
+
+ if not self.training:
+ original_entropy = entropy(logits)
+ highway_entropy = []
+ highway_logits_all = []
+ if labels is not None:
+ if self.num_labels == 1:
+ # We are doing regression
+ loss_fct = MSELoss()
+ loss = loss_fct(logits.view(-1), labels.view(-1))
+ else:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+
+ # work with highway exits
+ highway_losses = []
+ for highway_exit in outputs[-1]:
+ highway_logits = highway_exit[0]
+ if not self.training:
+ highway_logits_all.append(highway_logits)
+ highway_entropy.append(highway_exit[2])
+ if self.num_labels == 1:
+ # We are doing regression
+ loss_fct = MSELoss()
+ highway_loss = loss_fct(highway_logits.view(-1), labels.view(-1))
+ else:
+ loss_fct = CrossEntropyLoss()
+ highway_loss = loss_fct(highway_logits.view(-1, self.num_labels), labels.view(-1))
+ highway_losses.append(highway_loss)
+
+ if train_highway:
+ outputs = (sum(highway_losses[:-1]),) + outputs
+ # exclude the final highway, of course
+ else:
+ outputs = (loss,) + outputs
+ if not self.training:
+ outputs = outputs + ((original_entropy, highway_entropy), exit_layer)
+ if output_layer >= 0:
+ outputs = (
+ (outputs[0],) + (highway_logits_all[output_layer],) + outputs[2:]
+ ) # use the highway of the last layer
+
+ return outputs # (loss), logits, (hidden_states), (attentions), (highway_exits)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/src/modeling_highway_roberta.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/src/modeling_highway_roberta.py
new file mode 100644
index 0000000000000000000000000000000000000000..c21fb32fde762a8269f1f5b78b0e51e07b17f606
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/src/modeling_highway_roberta.py
@@ -0,0 +1,154 @@
+from __future__ import absolute_import, division, print_function, unicode_literals
+
+from torch import nn
+from torch.nn import CrossEntropyLoss, MSELoss
+
+from transformers import RobertaConfig
+from transformers.file_utils import add_start_docstrings, add_start_docstrings_to_model_forward
+from transformers.models.roberta.modeling_roberta import (
+ ROBERTA_INPUTS_DOCSTRING,
+ ROBERTA_START_DOCSTRING,
+ RobertaEmbeddings,
+)
+
+from .modeling_highway_bert import BertPreTrainedModel, DeeBertModel, HighwayException, entropy
+
+
+@add_start_docstrings(
+ "The RoBERTa Model transformer with early exiting (DeeRoBERTa). ",
+ ROBERTA_START_DOCSTRING,
+)
+class DeeRobertaModel(DeeBertModel):
+ config_class = RobertaConfig
+ base_model_prefix = "roberta"
+
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.embeddings = RobertaEmbeddings(config)
+ self.init_weights()
+
+
+@add_start_docstrings(
+ """RoBERTa Model (with early exiting - DeeRoBERTa) with a classifier on top,
+ also takes care of multi-layer training. """,
+ ROBERTA_START_DOCSTRING,
+)
+class DeeRobertaForSequenceClassification(BertPreTrainedModel):
+ config_class = RobertaConfig
+ base_model_prefix = "roberta"
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+ self.num_layers = config.num_hidden_layers
+
+ self.roberta = DeeRobertaModel(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.classifier = nn.Linear(config.hidden_size, self.config.num_labels)
+
+ @add_start_docstrings_to_model_forward(ROBERTA_INPUTS_DOCSTRING)
+ def forward(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ token_type_ids=None,
+ position_ids=None,
+ head_mask=None,
+ inputs_embeds=None,
+ labels=None,
+ output_layer=-1,
+ train_highway=False,
+ ):
+ r"""
+ labels (:obj:`torch.LongTensor` of shape :obj:`(batch_size,)`, `optional`):
+ Labels for computing the sequence classification/regression loss.
+ Indices should be in :obj:`[0, ..., config.num_labels - 1]`.
+ If :obj:`config.num_labels == 1` a regression loss is computed (Mean-Square loss),
+ If :obj:`config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+
+ Returns:
+ :obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.RobertaConfig`) and inputs:
+ loss (:obj:`torch.FloatTensor` of shape :obj:`(1,)`, `optional`, returned when :obj:`label` is provided):
+ Classification (or regression if config.num_labels==1) loss.
+ logits (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, config.num_labels)`):
+ Classification (or regression if config.num_labels==1) scores (before SoftMax).
+ hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_hidden_states=True`` is passed or when ``config.output_hidden_states=True``):
+ Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
+ of shape :obj:`(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
+ Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape
+ :obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ highway_exits (:obj:`tuple(tuple(torch.Tensor))`:
+ Tuple of each early exit's results (total length: number of layers)
+ Each tuple is again, a tuple of length 2 - the first entry is logits and the second entry is hidden states.
+ """
+
+ exit_layer = self.num_layers
+ try:
+ outputs = self.roberta(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ )
+
+ pooled_output = outputs[1]
+
+ pooled_output = self.dropout(pooled_output)
+ logits = self.classifier(pooled_output)
+ outputs = (logits,) + outputs[2:] # add hidden states and attention if they are here
+ except HighwayException as e:
+ outputs = e.message
+ exit_layer = e.exit_layer
+ logits = outputs[0]
+
+ if not self.training:
+ original_entropy = entropy(logits)
+ highway_entropy = []
+ highway_logits_all = []
+ if labels is not None:
+ if self.num_labels == 1:
+ # We are doing regression
+ loss_fct = MSELoss()
+ loss = loss_fct(logits.view(-1), labels.view(-1))
+ else:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+
+ # work with highway exits
+ highway_losses = []
+ for highway_exit in outputs[-1]:
+ highway_logits = highway_exit[0]
+ if not self.training:
+ highway_logits_all.append(highway_logits)
+ highway_entropy.append(highway_exit[2])
+ if self.num_labels == 1:
+ # We are doing regression
+ loss_fct = MSELoss()
+ highway_loss = loss_fct(highway_logits.view(-1), labels.view(-1))
+ else:
+ loss_fct = CrossEntropyLoss()
+ highway_loss = loss_fct(highway_logits.view(-1, self.num_labels), labels.view(-1))
+ highway_losses.append(highway_loss)
+
+ if train_highway:
+ outputs = (sum(highway_losses[:-1]),) + outputs
+ # exclude the final highway, of course
+ else:
+ outputs = (loss,) + outputs
+ if not self.training:
+ outputs = outputs + ((original_entropy, highway_entropy), exit_layer)
+ if output_layer >= 0:
+ outputs = (
+ (outputs[0],) + (highway_logits_all[output_layer],) + outputs[2:]
+ ) # use the highway of the last layer
+
+ return outputs # (loss), logits, (hidden_states), (attentions), entropy
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/test_glue_deebert.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/test_glue_deebert.py
new file mode 100644
index 0000000000000000000000000000000000000000..7a5f059c8cedff8cea2874f9dd521c02ee97300e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/test_glue_deebert.py
@@ -0,0 +1,104 @@
+import argparse
+import logging
+import sys
+from unittest.mock import patch
+
+import run_glue_deebert
+
+from transformers.testing_utils import TestCasePlus, get_gpu_count, require_torch_non_multi_gpu, slow
+
+
+logging.basicConfig(level=logging.DEBUG)
+
+logger = logging.getLogger()
+
+
+def get_setup_file():
+ parser = argparse.ArgumentParser()
+ parser.add_argument("-f")
+ args = parser.parse_args()
+ return args.f
+
+
+class DeeBertTests(TestCasePlus):
+ def setup(self) -> None:
+ stream_handler = logging.StreamHandler(sys.stdout)
+ logger.addHandler(stream_handler)
+
+ def run_and_check(self, args):
+ n_gpu = get_gpu_count()
+
+ if n_gpu > 1:
+ pass
+ # XXX: doesn't quite work with n_gpu > 1 https://github.com/huggingface/transformers/issues/10560
+ # script = f"{self.examples_dir_str}/research_projects/deebert/run_glue_deebert.py"
+ # distributed_args = f"-m torch.distributed.launch --nproc_per_node={n_gpu} {script}".split()
+ # cmd = [sys.executable] + distributed_args + args
+ # execute_subprocess_async(cmd, env=self.get_env())
+ # XXX: test the results - need to save them first into .json file
+ else:
+ args.insert(0, "run_glue_deebert.py")
+ with patch.object(sys, "argv", args):
+ result = run_glue_deebert.main()
+ for value in result.values():
+ self.assertGreaterEqual(value, 0.666)
+
+ @slow
+ @require_torch_non_multi_gpu
+ def test_glue_deebert_train(self):
+ train_args = """
+ --model_type roberta
+ --model_name_or_path FacebookAI/roberta-base
+ --task_name MRPC
+ --do_train
+ --do_eval
+ --do_lower_case
+ --data_dir ./tests/fixtures/tests_samples/MRPC/
+ --max_seq_length 128
+ --per_gpu_eval_batch_size=1
+ --per_gpu_train_batch_size=8
+ --learning_rate 2e-4
+ --num_train_epochs 3
+ --overwrite_output_dir
+ --seed 42
+ --output_dir ./examples/deebert/saved_models/FacebookAI/roberta-base/MRPC/two_stage
+ --plot_data_dir ./examples/deebert/results/
+ --save_steps 0
+ --overwrite_cache
+ --eval_after_first_stage
+ """.split()
+ self.run_and_check(train_args)
+
+ eval_args = """
+ --model_type roberta
+ --model_name_or_path ./examples/deebert/saved_models/FacebookAI/roberta-base/MRPC/two_stage
+ --task_name MRPC
+ --do_eval
+ --do_lower_case
+ --data_dir ./tests/fixtures/tests_samples/MRPC/
+ --output_dir ./examples/deebert/saved_models/FacebookAI/roberta-base/MRPC/two_stage
+ --plot_data_dir ./examples/deebert/results/
+ --max_seq_length 128
+ --eval_each_highway
+ --eval_highway
+ --overwrite_cache
+ --per_gpu_eval_batch_size=1
+ """.split()
+ self.run_and_check(eval_args)
+
+ entropy_eval_args = """
+ --model_type roberta
+ --model_name_or_path ./examples/deebert/saved_models/FacebookAI/roberta-base/MRPC/two_stage
+ --task_name MRPC
+ --do_eval
+ --do_lower_case
+ --data_dir ./tests/fixtures/tests_samples/MRPC/
+ --output_dir ./examples/deebert/saved_models/FacebookAI/roberta-base/MRPC/two_stage
+ --plot_data_dir ./examples/deebert/results/
+ --max_seq_length 128
+ --early_exit_entropy 0.1
+ --eval_highway
+ --overwrite_cache
+ --per_gpu_eval_batch_size=1
+ """.split()
+ self.run_and_check(entropy_eval_args)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/train_deebert.sh b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/train_deebert.sh
new file mode 100644
index 0000000000000000000000000000000000000000..32cdf5730f204e63ba9acf22c9d71656b701741a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/deebert/train_deebert.sh
@@ -0,0 +1,38 @@
+#!/bin/bash
+export CUDA_VISIBLE_DEVICES=0
+
+PATH_TO_DATA=/h/xinji/projects/GLUE
+
+MODEL_TYPE=bert # bert or roberta
+MODEL_SIZE=base # base or large
+DATASET=MRPC # SST-2, MRPC, RTE, QNLI, QQP, or MNLI
+
+MODEL_NAME=${MODEL_TYPE}-${MODEL_SIZE}
+EPOCHS=10
+if [ $MODEL_TYPE = 'bert' ]
+then
+ EPOCHS=3
+ MODEL_NAME=${MODEL_NAME}-uncased
+fi
+
+
+python -u run_glue_deebert.py \
+ --model_type $MODEL_TYPE \
+ --model_name_or_path $MODEL_NAME \
+ --task_name $DATASET \
+ --do_train \
+ --do_eval \
+ --do_lower_case \
+ --data_dir $PATH_TO_DATA/$DATASET \
+ --max_seq_length 128 \
+ --per_gpu_eval_batch_size=1 \
+ --per_gpu_train_batch_size=8 \
+ --learning_rate 2e-5 \
+ --num_train_epochs $EPOCHS \
+ --overwrite_output_dir \
+ --seed 42 \
+ --output_dir ./saved_models/${MODEL_TYPE}-${MODEL_SIZE}/$DATASET/two_stage \
+ --plot_data_dir ./results/ \
+ --save_steps 0 \
+ --overwrite_cache \
+ --eval_after_first_stage
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..594e953f99d76d09235cf430118d19a47edf170a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/README.md
@@ -0,0 +1,193 @@
+# Distil*
+
+Author: @VictorSanh
+
+This folder contains the original code used to train Distil* as well as examples showcasing how to use DistilBERT, DistilRoBERTa and DistilGPT2.
+
+**January 20, 2020 - Bug fixing** We have recently discovered and fixed [a bug](https://github.com/huggingface/transformers/commit/48cbf267c988b56c71a2380f748a3e6092ccaed3) in the evaluation of our `run_*.py` scripts that caused the reported metrics to be over-estimated on average. We have updated all the metrics with the latest runs.
+
+**December 6, 2019 - Update** We release **DistilmBERT**: 92% of `bert-base-multilingual-cased` on XNLI. The model supports 104 different languages listed [here](https://github.com/google-research/bert/blob/master/multilingual.md#list-of-languages).
+
+**November 19, 2019 - Update** We release German **DistilBERT**: 98.8% of `bert-base-german-dbmdz-cased` on NER tasks.
+
+**October 23, 2019 - Update** We release **DistilRoBERTa**: 95% of `RoBERTa-base`'s performance on GLUE, twice as fast as RoBERTa while being 35% smaller.
+
+**October 3, 2019 - Update** We release our [NeurIPS workshop paper](https://arxiv.org/abs/1910.01108) explaining our approach on **DistilBERT**. It includes updated results and further experiments. We applied the same method to GPT2 and release the weights of **DistilGPT2**. DistilGPT2 is two times faster and 33% smaller than GPT2. **The paper supersedes our [previous blogpost](https://medium.com/huggingface/distilbert-8cf3380435b5) with a different distillation loss and better performances. Please use the paper as a reference when comparing/reporting results on DistilBERT.**
+
+**September 19, 2019 - Update:** We fixed bugs in the code and released an updated version of the weights trained with a modification of the distillation loss. DistilBERT now reaches 99% of `BERT-base`'s performance on GLUE, and 86.9 F1 score on SQuAD v1.1 dev set (compared to 88.5 for `BERT-base`). We will publish a formal write-up of our approach in the near future!
+
+
+## What is Distil*
+
+Distil* is a class of compressed models that started with DistilBERT. DistilBERT stands for Distilled-BERT. DistilBERT is a small, fast, cheap and light Transformer model based on Bert architecture. It has 40% less parameters than `bert-base-uncased`, runs 60% faster while preserving 97% of BERT's performances as measured on the GLUE language understanding benchmark. DistilBERT is trained using knowledge distillation, a technique to compress a large model called the teacher into a smaller model called the student. By distillating Bert, we obtain a smaller Transformer model that bears a lot of similarities with the original BERT model while being lighter, smaller and faster to run. DistilBERT is thus an interesting option to put large-scaled trained Transformer model into production.
+
+We have applied the same method to other Transformer architectures and released the weights:
+- GPT2: on the [WikiText-103](https://blog.einstein.ai/the-wikitext-long-term-dependency-language-modeling-dataset/) benchmark, GPT2 reaches a perplexity on the test set of 16.3 compared to 21.1 for **DistilGPT2** (after fine-tuning on the train set).
+- RoBERTa: **DistilRoBERTa** reaches 95% of `RoBERTa-base`'s performance on GLUE while being twice faster and 35% smaller.
+- German BERT: **German DistilBERT** reaches 99% of `bert-base-german-dbmdz-cased`'s performance on German NER (CoNLL-2003).
+- Multilingual BERT: **DistilmBERT** reaches 92% of Multilingual BERT's performance on XNLI while being twice faster and 25% smaller. The model supports 104 languages listed [here](https://github.com/google-research/bert/blob/master/multilingual.md#list-of-languages).
+
+For more information on DistilBERT, please refer to our [NeurIPS workshop paper](https://arxiv.org/abs/1910.01108).
+
+Here are the results on the dev sets of GLUE:
+
+| Model | Macro-score | CoLA | MNLI | MRPC | QNLI | QQP | RTE | SST-2| STS-B| WNLI |
+| :---: | :---: | :---:| :---:| :---:| :---:| :---:| :---:| :---:| :---:| :---: |
+| BERT-base-uncased | **79.5** | 56.3 | 84.7 | 88.6 | 91.8 | 89.6 | 69.3 | 92.7 | 89.0 | 53.5 |
+| DistilBERT-base-uncased | **77.0** | 51.3 | 82.1 | 87.5 | 89.2 | 88.5 | 59.9 | 91.3 | 86.9 | 56.3 |
+| BERT-base-cased | **78.2** | 58.2 | 83.9 | 87.8 | 91.0 | 89.2 | 66.1 | 91.7 | 89.2 | 46.5 |
+| DistilBERT-base-cased | **75.9** | 47.2 | 81.5 | 85.6 | 88.2 | 87.8 | 60.6 | 90.4 | 85.5 | 56.3 |
+| --- | --- | --- | --- | --- | --- | --- | --- | --- | --- | --- |
+| RoBERTa-base (reported) | **83.2**/**86.4**2 | 63.6 | 87.6 | 90.2 | 92.8 | 91.9 | 78.7 | 94.8 | 91.2 | 57.73 |
+| DistilRoBERTa1 | **79.0**/**82.3**2 | 59.3 | 84.0 | 86.6 | 90.8 | 89.4 | 67.9 | 92.5 | 88.3 | 52.1 |
+
+1 We did not use the MNLI checkpoint for fine-tuning but directly perform transfer learning on the pre-trained DistilRoBERTa.
+
+2 Macro-score computed without WNLI.
+
+3 We compute this score ourselves for completeness.
+
+Here are the results on the *test* sets for 6 of the languages available in XNLI. The results are computed in the zero shot setting (trained on the English portion and evaluated on the target language portion):
+
+| Model | English | Spanish | Chinese | German | Arabic | Urdu |
+| :---: | :---: | :---: | :---: | :---: | :---: | :---:|
+| mBERT base cased (computed) | 82.1 | 74.6 | 69.1 | 72.3 | 66.4 | 58.5 |
+| mBERT base uncased (reported)| 81.4 | 74.3 | 63.8 | 70.5 | 62.1 | 58.3 |
+| DistilmBERT | 78.2 | 69.1 | 64.0 | 66.3 | 59.1 | 54.7 |
+
+## Setup
+
+This part of the library has only be tested with Python3.6+. There are few specific dependencies to install before launching a distillation, you can install them with the command `pip install -r requirements.txt`.
+
+**Important note:** The training scripts have been updated to support PyTorch v1.2.0 (there are breaking changes compared to v1.1.0).
+
+
+## How to use DistilBERT
+
+Transformers includes five pre-trained Distil* models, currently only provided for English and German (we are investigating the possibility to train and release a multilingual version of DistilBERT):
+
+- `distilbert-base-uncased`: DistilBERT English language model pretrained on the same data used to pretrain Bert (concatenation of the Toronto Book Corpus and full English Wikipedia) using distillation with the supervision of the `bert-base-uncased` version of Bert. The model has 6 layers, 768 dimension and 12 heads, totalizing 66M parameters.
+- `distilbert-base-uncased-distilled-squad`: A finetuned version of `distilbert-base-uncased` finetuned using (a second step of) knowledge distillation on SQuAD 1.0. This model reaches a F1 score of 86.9 on the dev set (for comparison, Bert `bert-base-uncased` version reaches a 88.5 F1 score).
+- `distilbert-base-cased`: DistilBERT English language model pretrained on the same data used to pretrain Bert (concatenation of the Toronto Book Corpus and full English Wikipedia) using distillation with the supervision of the `bert-base-cased` version of Bert. The model has 6 layers, 768 dimension and 12 heads, totalizing 65M parameters.
+- `distilbert-base-cased-distilled-squad`: A finetuned version of `distilbert-base-cased` finetuned using (a second step of) knowledge distillation on SQuAD 1.0. This model reaches a F1 score of 87.1 on the dev set (for comparison, Bert `bert-base-cased` version reaches a 88.7 F1 score).
+- `distilbert-base-german-cased`: DistilBERT German language model pretrained on 1/2 of the data used to pretrain Bert using distillation with the supervision of the `bert-base-german-dbmdz-cased` version of German DBMDZ Bert. For NER tasks the model reaches a F1 score of 83.49 on the CoNLL-2003 test set (for comparison, `bert-base-german-dbmdz-cased` reaches a 84.52 F1 score), and a F1 score of 85.23 on the GermEval 2014 test set (`bert-base-german-dbmdz-cased` reaches a 86.89 F1 score).
+- `distilgpt2`: DistilGPT2 English language model pretrained with the supervision of `gpt2` (the smallest version of GPT2) on [OpenWebTextCorpus](https://skylion007.github.io/OpenWebTextCorpus/), a reproduction of OpenAI's WebText dataset. The model has 6 layers, 768 dimension and 12 heads, totalizing 82M parameters (compared to 124M parameters for GPT2). On average, DistilGPT2 is two times faster than GPT2.
+- `distilroberta-base`: DistilRoBERTa English language model pretrained with the supervision of `roberta-base` solely on [OpenWebTextCorpus](https://skylion007.github.io/OpenWebTextCorpus/), a reproduction of OpenAI's WebText dataset (it is ~4 times less training data than the teacher RoBERTa). The model has 6 layers, 768 dimension and 12 heads, totalizing 82M parameters (compared to 125M parameters for RoBERTa-base). On average DistilRoBERTa is twice as fast as Roberta-base.
+- `distilbert-base-multilingual-cased`: DistilmBERT multilingual model pretrained with the supervision of `bert-base-multilingual-cased` on the concatenation of Wikipedia in 104 different languages. The model supports the 104 languages listed [here](https://github.com/google-research/bert/blob/master/multilingual.md#list-of-languages). The model has 6 layers, 768 dimension and 12 heads, totalizing 134M parameters (compared to 177M parameters for mBERT-base). On average DistilmBERT is twice as fast as mBERT-base.
+
+Using DistilBERT is very similar to using BERT. DistilBERT share the same tokenizer as BERT's `bert-base-uncased` even though we provide a link to this tokenizer under the `DistilBertTokenizer` name to have a consistent naming between the library models.
+
+```python
+tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
+model = DistilBertModel.from_pretrained('distilbert-base-cased')
+
+input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute")).unsqueeze(0)
+outputs = model(input_ids)
+last_hidden_states = outputs[0] # The last hidden-state is the first element of the output tuple
+```
+
+Similarly, using the other Distil* models simply consists in calling the base classes with a different pretrained checkpoint:
+- DistilBERT uncased: `model = DistilBertModel.from_pretrained('distilbert-base-uncased')`
+- DistilGPT2: `model = GPT2Model.from_pretrained('distilgpt2')`
+- DistilRoBERTa: `model = RobertaModel.from_pretrained('distilroberta-base')`
+- DistilmBERT: `model = DistilBertModel.from_pretrained('distilbert-base-multilingual-cased')`
+
+
+## How to train Distil*
+
+In the following, we will explain how you can train DistilBERT.
+
+### A. Preparing the data
+
+The weights we release are trained using a concatenation of Toronto Book Corpus and English Wikipedia (same training data as the English version of BERT).
+
+To avoid processing the data several time, we do it once and for all before the training. From now on, will suppose that you have a text file `dump.txt` which contains one sequence per line (a sequence being composed of one of several coherent sentences).
+
+First, we will binarize the data, i.e. tokenize the data and convert each token in an index in our model's vocabulary.
+
+```bash
+python scripts/binarized_data.py \
+ --file_path data/dump.txt \
+ --tokenizer_type bert \
+ --tokenizer_name bert-base-uncased \
+ --dump_file data/binarized_text
+```
+
+Our implementation of masked language modeling loss follows [XLM](https://github.com/facebookresearch/XLM)'s one and smooths the probability of masking with a factor that put more emphasis on rare words. Thus we count the occurrences of each tokens in the data:
+
+```bash
+python scripts/token_counts.py \
+ --data_file data/binarized_text.bert-base-uncased.pickle \
+ --token_counts_dump data/token_counts.bert-base-uncased.pickle \
+ --vocab_size 30522
+```
+
+### B. Training
+
+Training with distillation is really simple once you have pre-processed the data:
+
+```bash
+python train.py \
+ --student_type distilbert \
+ --student_config training_configs/distilbert-base-uncased.json \
+ --teacher_type bert \
+ --teacher_name bert-base-uncased \
+ --alpha_ce 5.0 --alpha_mlm 2.0 --alpha_cos 1.0 --alpha_clm 0.0 --mlm \
+ --freeze_pos_embs \
+ --dump_path serialization_dir/my_first_training \
+ --data_file data/binarized_text.bert-base-uncased.pickle \
+ --token_counts data/token_counts.bert-base-uncased.pickle \
+ --force # overwrites the `dump_path` if it already exists.
+```
+
+By default, this will launch a training on a single GPU (even if more are available on the cluster). Other parameters are available in the command line, please look in `train.py` or run `python train.py --help` to list them.
+
+We highly encourage you to use distributed training for training DistilBERT as the training corpus is quite large. Here's an example that runs a distributed training on a single node having 4 GPUs:
+
+```bash
+export NODE_RANK=0
+export N_NODES=1
+
+export N_GPU_NODE=4
+export WORLD_SIZE=4
+export MASTER_PORT=
+export MASTER_ADDR=
+
+pkill -f 'python -u train.py'
+
+python -m torch.distributed.launch \
+ --nproc_per_node=$N_GPU_NODE \
+ --nnodes=$N_NODES \
+ --node_rank $NODE_RANK \
+ --master_addr $MASTER_ADDR \
+ --master_port $MASTER_PORT \
+ train.py \
+ --force \
+ --n_gpu $WORLD_SIZE \
+ --student_type distilbert \
+ --student_config training_configs/distilbert-base-uncased.json \
+ --teacher_type bert \
+ --teacher_name bert-base-uncased \
+ --alpha_ce 0.33 --alpha_mlm 0.33 --alpha_cos 0.33 --alpha_clm 0.0 --mlm \
+ --freeze_pos_embs \
+ --dump_path serialization_dir/my_first_training \
+ --data_file data/binarized_text.bert-base-uncased.pickle \
+ --token_counts data/token_counts.bert-base-uncased.pickle
+```
+
+**Tips:** Starting distilled training with good initialization of the model weights is crucial to reach decent performance. In our experiments, we initialized our model from a few layers of the teacher (Bert) itself! Please refer to `scripts/extract.py` and `scripts/extract_distilbert.py` to create a valid initialization checkpoint and use `--student_pretrained_weights` argument to use this initialization for the distilled training!
+
+Happy distillation!
+
+## Citation
+
+If you find the resource useful, you should cite the following paper:
+
+```bibtex
+@inproceedings{sanh2019distilbert,
+ title={DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter},
+ author={Sanh, Victor and Debut, Lysandre and Chaumond, Julien and Wolf, Thomas},
+ booktitle={NeurIPS EMC^2 Workshop},
+ year={2019}
+}
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/distiller.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/distiller.py
new file mode 100644
index 0000000000000000000000000000000000000000..963af976f5a4a9e8b207e6a11e3b31b6cdb278a2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/distiller.py
@@ -0,0 +1,601 @@
+# coding=utf-8
+# Copyright 2019-present, the HuggingFace Inc. team and Facebook, Inc.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""The distiller to distil the student.
+Adapted in part from Facebook, Inc XLM model (https://github.com/facebookresearch/XLM)
+"""
+
+import math
+import os
+import time
+
+import psutil
+import torch
+from grouped_batch_sampler import GroupedBatchSampler, create_lengths_groups
+from lm_seqs_dataset import LmSeqsDataset
+from torch import nn
+from torch.optim import AdamW
+from torch.utils.data import BatchSampler, DataLoader, RandomSampler
+from torch.utils.data.distributed import DistributedSampler
+from tqdm import tqdm
+
+from transformers import get_linear_schedule_with_warmup
+from utils import logger
+
+
+try:
+ from torch.utils.tensorboard import SummaryWriter
+except ImportError:
+ from tensorboardX import SummaryWriter
+
+
+class Distiller:
+ def __init__(
+ self, params: dict, dataset: LmSeqsDataset, token_probs: torch.tensor, student: nn.Module, teacher: nn.Module
+ ):
+ logger.info("Initializing Distiller")
+ self.params = params
+ self.dump_path = params.dump_path
+ self.multi_gpu = params.multi_gpu
+ self.fp16 = params.fp16
+
+ self.student = student
+ self.teacher = teacher
+
+ self.student_config = student.config
+ self.vocab_size = student.config.vocab_size
+
+ if params.n_gpu <= 1:
+ sampler = RandomSampler(dataset)
+ else:
+ sampler = DistributedSampler(dataset)
+
+ if params.group_by_size:
+ groups = create_lengths_groups(lengths=dataset.lengths, k=params.max_model_input_size)
+ sampler = GroupedBatchSampler(sampler=sampler, group_ids=groups, batch_size=params.batch_size)
+ else:
+ sampler = BatchSampler(sampler=sampler, batch_size=params.batch_size, drop_last=False)
+
+ self.dataloader = DataLoader(dataset=dataset, batch_sampler=sampler, collate_fn=dataset.batch_sequences)
+
+ self.temperature = params.temperature
+ assert self.temperature > 0.0
+
+ self.alpha_ce = params.alpha_ce
+ self.alpha_mlm = params.alpha_mlm
+ self.alpha_clm = params.alpha_clm
+ self.alpha_mse = params.alpha_mse
+ self.alpha_cos = params.alpha_cos
+
+ self.mlm = params.mlm
+ if self.mlm:
+ logger.info("Using MLM loss for LM step.")
+ self.mlm_mask_prop = params.mlm_mask_prop
+ assert 0.0 <= self.mlm_mask_prop <= 1.0
+ assert params.word_mask + params.word_keep + params.word_rand == 1.0
+ self.pred_probs = torch.FloatTensor([params.word_mask, params.word_keep, params.word_rand])
+ self.pred_probs = self.pred_probs.to(f"cuda:{params.local_rank}") if params.n_gpu > 0 else self.pred_probs
+ self.token_probs = token_probs.to(f"cuda:{params.local_rank}") if params.n_gpu > 0 else token_probs
+ if self.fp16:
+ self.pred_probs = self.pred_probs.half()
+ self.token_probs = self.token_probs.half()
+ else:
+ logger.info("Using CLM loss for LM step.")
+
+ self.epoch = 0
+ self.n_iter = 0
+ self.n_total_iter = 0
+ self.n_sequences_epoch = 0
+ self.total_loss_epoch = 0
+ self.last_loss = 0
+ self.last_loss_ce = 0
+ self.last_loss_mlm = 0
+ self.last_loss_clm = 0
+ if self.alpha_mse > 0.0:
+ self.last_loss_mse = 0
+ if self.alpha_cos > 0.0:
+ self.last_loss_cos = 0
+ self.last_log = 0
+
+ self.ce_loss_fct = nn.KLDivLoss(reduction="batchmean")
+ self.lm_loss_fct = nn.CrossEntropyLoss(ignore_index=-100)
+ if self.alpha_mse > 0.0:
+ self.mse_loss_fct = nn.MSELoss(reduction="sum")
+ if self.alpha_cos > 0.0:
+ self.cosine_loss_fct = nn.CosineEmbeddingLoss(reduction="mean")
+
+ logger.info("--- Initializing model optimizer")
+ assert params.gradient_accumulation_steps >= 1
+ self.num_steps_epoch = len(self.dataloader)
+ num_train_optimization_steps = (
+ int(self.num_steps_epoch / params.gradient_accumulation_steps * params.n_epoch) + 1
+ )
+
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [
+ p for n, p in student.named_parameters() if not any(nd in n for nd in no_decay) and p.requires_grad
+ ],
+ "weight_decay": params.weight_decay,
+ },
+ {
+ "params": [
+ p for n, p in student.named_parameters() if any(nd in n for nd in no_decay) and p.requires_grad
+ ],
+ "weight_decay": 0.0,
+ },
+ ]
+ logger.info(
+ "------ Number of trainable parameters (student): %i"
+ % sum([p.numel() for p in self.student.parameters() if p.requires_grad])
+ )
+ logger.info("------ Number of parameters (student): %i" % sum([p.numel() for p in self.student.parameters()]))
+ self.optimizer = AdamW(
+ optimizer_grouped_parameters, lr=params.learning_rate, eps=params.adam_epsilon, betas=(0.9, 0.98)
+ )
+
+ warmup_steps = math.ceil(num_train_optimization_steps * params.warmup_prop)
+ self.scheduler = get_linear_schedule_with_warmup(
+ self.optimizer, num_warmup_steps=warmup_steps, num_training_steps=num_train_optimization_steps
+ )
+
+ if self.fp16:
+ try:
+ from apex import amp
+ except ImportError:
+ raise ImportError("Please install apex from https://www.github.com/nvidia/apex to use fp16 training.")
+ logger.info(f"Using fp16 training: {self.params.fp16_opt_level} level")
+ self.student, self.optimizer = amp.initialize(
+ self.student, self.optimizer, opt_level=self.params.fp16_opt_level
+ )
+ self.teacher = self.teacher.half()
+
+ if self.multi_gpu:
+ if self.fp16:
+ from apex.parallel import DistributedDataParallel
+
+ logger.info("Using apex.parallel.DistributedDataParallel for distributed training.")
+ self.student = DistributedDataParallel(self.student)
+ else:
+ from torch.nn.parallel import DistributedDataParallel
+
+ logger.info("Using nn.parallel.DistributedDataParallel for distributed training.")
+ self.student = DistributedDataParallel(
+ self.student,
+ device_ids=[params.local_rank],
+ output_device=params.local_rank,
+ find_unused_parameters=True,
+ )
+
+ self.is_master = params.is_master
+ if self.is_master:
+ logger.info("--- Initializing Tensorboard")
+ self.tensorboard = SummaryWriter(log_dir=os.path.join(self.dump_path, "log", "train"))
+ self.tensorboard.add_text(tag="config/training", text_string=str(self.params), global_step=0)
+ self.tensorboard.add_text(tag="config/student", text_string=str(self.student_config), global_step=0)
+
+ def prepare_batch_mlm(self, batch):
+ """
+ Prepare the batch: from the token_ids and the lengths, compute the attention mask and the masked label for MLM.
+
+ Input:
+ ------
+ batch: `Tuple`
+ token_ids: `torch.tensor(bs, seq_length)` - The token ids for each of the sequence. It is padded.
+ lengths: `torch.tensor(bs)` - The lengths of each of the sequences in the batch.
+
+ Output:
+ -------
+ token_ids: `torch.tensor(bs, seq_length)` - The token ids after the modifications for MLM.
+ attn_mask: `torch.tensor(bs, seq_length)` - The attention mask for the self-attention.
+ mlm_labels: `torch.tensor(bs, seq_length)` - The masked language modeling labels. There is a -100 where there is nothing to predict.
+ """
+ token_ids, lengths = batch
+ token_ids, lengths = self.round_batch(x=token_ids, lengths=lengths)
+ assert token_ids.size(0) == lengths.size(0)
+
+ attn_mask = torch.arange(token_ids.size(1), dtype=torch.long, device=lengths.device) < lengths[:, None]
+
+ bs, max_seq_len = token_ids.size()
+ mlm_labels = token_ids.new(token_ids.size()).copy_(token_ids)
+
+ x_prob = self.token_probs[token_ids.flatten()]
+ n_tgt = math.ceil(self.mlm_mask_prop * lengths.sum().item())
+ tgt_ids = torch.multinomial(x_prob / x_prob.sum(), n_tgt, replacement=False)
+ pred_mask = torch.zeros(
+ bs * max_seq_len, dtype=torch.bool, device=token_ids.device
+ ) # previously `dtype=torch.uint8`, cf pytorch 1.2.0 compatibility
+ pred_mask[tgt_ids] = 1
+ pred_mask = pred_mask.view(bs, max_seq_len)
+
+ pred_mask[token_ids == self.params.special_tok_ids["pad_token"]] = 0
+
+ # mask a number of words == 0 [8] (faster with fp16)
+ if self.fp16:
+ n1 = pred_mask.sum().item()
+ if n1 > 8:
+ pred_mask = pred_mask.view(-1)
+ n2 = max(n1 % 8, 8 * (n1 // 8))
+ if n2 != n1:
+ pred_mask[torch.nonzero(pred_mask).view(-1)[: n1 - n2]] = 0
+ pred_mask = pred_mask.view(bs, max_seq_len)
+ assert pred_mask.sum().item() % 8 == 0, pred_mask.sum().item()
+
+ _token_ids_real = token_ids[pred_mask]
+ _token_ids_rand = _token_ids_real.clone().random_(self.vocab_size)
+ _token_ids_mask = _token_ids_real.clone().fill_(self.params.special_tok_ids["mask_token"])
+ probs = torch.multinomial(self.pred_probs, len(_token_ids_real), replacement=True)
+ _token_ids = (
+ _token_ids_mask * (probs == 0).long()
+ + _token_ids_real * (probs == 1).long()
+ + _token_ids_rand * (probs == 2).long()
+ )
+ token_ids = token_ids.masked_scatter(pred_mask, _token_ids)
+
+ mlm_labels[~pred_mask] = -100 # previously `mlm_labels[1-pred_mask] = -1`, cf pytorch 1.2.0 compatibility
+
+ # sanity checks
+ assert 0 <= token_ids.min() <= token_ids.max() < self.vocab_size
+
+ return token_ids, attn_mask, mlm_labels
+
+ def prepare_batch_clm(self, batch):
+ """
+ Prepare the batch: from the token_ids and the lengths, compute the attention mask and the labels for CLM.
+
+ Input:
+ ------
+ batch: `Tuple`
+ token_ids: `torch.tensor(bs, seq_length)` - The token ids for each of the sequence. It is padded.
+ lengths: `torch.tensor(bs)` - The lengths of each of the sequences in the batch.
+
+ Output:
+ -------
+ token_ids: `torch.tensor(bs, seq_length)` - The token ids after the modifications for MLM.
+ attn_mask: `torch.tensor(bs, seq_length)` - The attention mask for the self-attention.
+ clm_labels: `torch.tensor(bs, seq_length)` - The causal language modeling labels. There is a -100 where there is nothing to predict.
+ """
+ token_ids, lengths = batch
+ token_ids, lengths = self.round_batch(x=token_ids, lengths=lengths)
+ assert token_ids.size(0) == lengths.size(0)
+
+ attn_mask = torch.arange(token_ids.size(1), dtype=torch.long, device=lengths.device) < lengths[:, None]
+ clm_labels = token_ids.new(token_ids.size()).copy_(token_ids)
+ clm_labels[~attn_mask] = -100 # previously `clm_labels[1-attn_mask] = -1`, cf pytorch 1.2.0 compatibility
+
+ # sanity checks
+ assert 0 <= token_ids.min() <= token_ids.max() < self.vocab_size
+
+ return token_ids, attn_mask, clm_labels
+
+ def round_batch(self, x: torch.tensor, lengths: torch.tensor):
+ """
+ For float16 only.
+ Sub-sample sentences in a batch, and add padding, so that each dimension is a multiple of 8.
+
+ Input:
+ ------
+ x: `torch.tensor(bs, seq_length)` - The token ids.
+ lengths: `torch.tensor(bs, seq_length)` - The lengths of each of the sequence in the batch.
+
+ Output:
+ -------
+ x: `torch.tensor(new_bs, new_seq_length)` - The updated token ids.
+ lengths: `torch.tensor(new_bs, new_seq_length)` - The updated lengths.
+ """
+ if not self.fp16 or len(lengths) < 8:
+ return x, lengths
+
+ # number of sentences == 0 [8]
+ bs1 = len(lengths)
+ bs2 = 8 * (bs1 // 8)
+ assert bs2 > 0 and bs2 % 8 == 0
+ if bs1 != bs2:
+ idx = torch.randperm(bs1)[:bs2]
+ lengths = lengths[idx]
+ slen = lengths.max().item()
+ x = x[idx, :slen]
+ else:
+ idx = None
+
+ # sequence length == 0 [8]
+ ml1 = x.size(1)
+ if ml1 % 8 != 0:
+ pad = 8 - (ml1 % 8)
+ ml2 = ml1 + pad
+ if self.mlm:
+ pad_id = self.params.special_tok_ids["pad_token"]
+ else:
+ pad_id = self.params.special_tok_ids["unk_token"]
+ padding_tensor = torch.zeros(bs2, pad, dtype=torch.long, device=x.device).fill_(pad_id)
+ x = torch.cat([x, padding_tensor], 1)
+ assert x.size() == (bs2, ml2)
+
+ assert x.size(0) % 8 == 0
+ assert x.size(1) % 8 == 0
+ return x, lengths
+
+ def train(self):
+ """
+ The real training loop.
+ """
+ if self.is_master:
+ logger.info("Starting training")
+ self.last_log = time.time()
+ self.student.train()
+ self.teacher.eval()
+
+ for _ in range(self.params.n_epoch):
+ if self.is_master:
+ logger.info(f"--- Starting epoch {self.epoch}/{self.params.n_epoch-1}")
+ if self.multi_gpu:
+ torch.distributed.barrier()
+
+ iter_bar = tqdm(self.dataloader, desc="-Iter", disable=self.params.local_rank not in [-1, 0])
+ for batch in iter_bar:
+ if self.params.n_gpu > 0:
+ batch = tuple(t.to(f"cuda:{self.params.local_rank}") for t in batch)
+
+ if self.mlm:
+ token_ids, attn_mask, lm_labels = self.prepare_batch_mlm(batch=batch)
+ else:
+ token_ids, attn_mask, lm_labels = self.prepare_batch_clm(batch=batch)
+ self.step(input_ids=token_ids, attention_mask=attn_mask, lm_labels=lm_labels)
+
+ iter_bar.update()
+ iter_bar.set_postfix(
+ {"Last_loss": f"{self.last_loss:.2f}", "Avg_cum_loss": f"{self.total_loss_epoch/self.n_iter:.2f}"}
+ )
+ iter_bar.close()
+
+ if self.is_master:
+ logger.info(f"--- Ending epoch {self.epoch}/{self.params.n_epoch-1}")
+ self.end_epoch()
+
+ if self.is_master:
+ logger.info("Save very last checkpoint as `pytorch_model.bin`.")
+ self.save_checkpoint(checkpoint_name="pytorch_model.bin")
+ logger.info("Training is finished")
+
+ def step(self, input_ids: torch.tensor, attention_mask: torch.tensor, lm_labels: torch.tensor):
+ """
+ One optimization step: forward of student AND teacher, backward on the loss (for gradient accumulation),
+ and possibly a parameter update (depending on the gradient accumulation).
+
+ Input:
+ ------
+ input_ids: `torch.tensor(bs, seq_length)` - The token ids.
+ attention_mask: `torch.tensor(bs, seq_length)` - The attention mask for self attention.
+ lm_labels: `torch.tensor(bs, seq_length)` - The language modeling labels (mlm labels for MLM and clm labels for CLM).
+ """
+ if self.mlm:
+ student_outputs = self.student(
+ input_ids=input_ids, attention_mask=attention_mask
+ ) # (bs, seq_length, voc_size)
+ with torch.no_grad():
+ teacher_outputs = self.teacher(
+ input_ids=input_ids, attention_mask=attention_mask
+ ) # (bs, seq_length, voc_size)
+ else:
+ student_outputs = self.student(input_ids=input_ids, attention_mask=None) # (bs, seq_length, voc_size)
+ with torch.no_grad():
+ teacher_outputs = self.teacher(input_ids=input_ids, attention_mask=None) # (bs, seq_length, voc_size)
+ s_logits, s_hidden_states = student_outputs["logits"], student_outputs["hidden_states"]
+ t_logits, t_hidden_states = teacher_outputs["logits"], teacher_outputs["hidden_states"]
+ assert s_logits.size() == t_logits.size()
+
+ # https://github.com/peterliht/knowledge-distillation-pytorch/blob/master/model/net.py#L100
+ # https://github.com/peterliht/knowledge-distillation-pytorch/issues/2
+ if self.params.restrict_ce_to_mask:
+ mask = (lm_labels > -1).unsqueeze(-1).expand_as(s_logits) # (bs, seq_length, voc_size)
+ else:
+ mask = attention_mask.unsqueeze(-1).expand_as(s_logits) # (bs, seq_length, voc_size)
+ s_logits_slct = torch.masked_select(s_logits, mask) # (bs * seq_length * voc_size) modulo the 1s in mask
+ s_logits_slct = s_logits_slct.view(-1, s_logits.size(-1)) # (bs * seq_length, voc_size) modulo the 1s in mask
+ t_logits_slct = torch.masked_select(t_logits, mask) # (bs * seq_length * voc_size) modulo the 1s in mask
+ t_logits_slct = t_logits_slct.view(-1, s_logits.size(-1)) # (bs * seq_length, voc_size) modulo the 1s in mask
+ assert t_logits_slct.size() == s_logits_slct.size()
+
+ loss_ce = (
+ self.ce_loss_fct(
+ nn.functional.log_softmax(s_logits_slct / self.temperature, dim=-1),
+ nn.functional.softmax(t_logits_slct / self.temperature, dim=-1),
+ )
+ * (self.temperature) ** 2
+ )
+ loss = self.alpha_ce * loss_ce
+
+ if self.alpha_mlm > 0.0:
+ loss_mlm = self.lm_loss_fct(s_logits.view(-1, s_logits.size(-1)), lm_labels.view(-1))
+ loss += self.alpha_mlm * loss_mlm
+ if self.alpha_clm > 0.0:
+ shift_logits = s_logits[..., :-1, :].contiguous()
+ shift_labels = lm_labels[..., 1:].contiguous()
+ loss_clm = self.lm_loss_fct(shift_logits.view(-1, shift_logits.size(-1)), shift_labels.view(-1))
+ loss += self.alpha_clm * loss_clm
+
+ if self.alpha_mse > 0.0:
+ loss_mse = self.mse_loss_fct(s_logits_slct, t_logits_slct) / s_logits_slct.size(
+ 0
+ ) # Reproducing batchmean reduction
+ loss += self.alpha_mse * loss_mse
+ if self.alpha_cos > 0.0:
+ s_hidden_states = s_hidden_states[-1] # (bs, seq_length, dim)
+ t_hidden_states = t_hidden_states[-1] # (bs, seq_length, dim)
+ mask = attention_mask.unsqueeze(-1).expand_as(s_hidden_states) # (bs, seq_length, dim)
+ assert s_hidden_states.size() == t_hidden_states.size()
+ dim = s_hidden_states.size(-1)
+
+ s_hidden_states_slct = torch.masked_select(s_hidden_states, mask) # (bs * seq_length * dim)
+ s_hidden_states_slct = s_hidden_states_slct.view(-1, dim) # (bs * seq_length, dim)
+ t_hidden_states_slct = torch.masked_select(t_hidden_states, mask) # (bs * seq_length * dim)
+ t_hidden_states_slct = t_hidden_states_slct.view(-1, dim) # (bs * seq_length, dim)
+
+ target = s_hidden_states_slct.new(s_hidden_states_slct.size(0)).fill_(1) # (bs * seq_length,)
+ loss_cos = self.cosine_loss_fct(s_hidden_states_slct, t_hidden_states_slct, target)
+ loss += self.alpha_cos * loss_cos
+
+ self.total_loss_epoch += loss.item()
+ self.last_loss = loss.item()
+ self.last_loss_ce = loss_ce.item()
+ if self.alpha_mlm > 0.0:
+ self.last_loss_mlm = loss_mlm.item()
+ if self.alpha_clm > 0.0:
+ self.last_loss_clm = loss_clm.item()
+ if self.alpha_mse > 0.0:
+ self.last_loss_mse = loss_mse.item()
+ if self.alpha_cos > 0.0:
+ self.last_loss_cos = loss_cos.item()
+
+ self.optimize(loss)
+
+ self.n_sequences_epoch += input_ids.size(0)
+
+ def optimize(self, loss):
+ """
+ Normalization on the loss (gradient accumulation or distributed training), followed by
+ backward pass on the loss, possibly followed by a parameter update (depending on the gradient accumulation).
+ Also update the metrics for tensorboard.
+ """
+ # Check for NaN
+ if (loss != loss).data.any():
+ logger.error("NaN detected")
+ exit()
+
+ if self.multi_gpu:
+ loss = loss.mean()
+ if self.params.gradient_accumulation_steps > 1:
+ loss = loss / self.params.gradient_accumulation_steps
+
+ if self.fp16:
+ from apex import amp
+
+ with amp.scale_loss(loss, self.optimizer) as scaled_loss:
+ scaled_loss.backward()
+ else:
+ loss.backward()
+
+ self.iter()
+ if self.n_iter % self.params.gradient_accumulation_steps == 0:
+ if self.fp16:
+ nn.utils.clip_grad_norm_(amp.master_params(self.optimizer), self.params.max_grad_norm)
+ else:
+ nn.utils.clip_grad_norm_(self.student.parameters(), self.params.max_grad_norm)
+ self.optimizer.step()
+ self.optimizer.zero_grad()
+ self.scheduler.step()
+
+ def iter(self):
+ """
+ Update global counts, write to tensorboard and save checkpoint.
+ """
+ self.n_iter += 1
+ self.n_total_iter += 1
+
+ if self.n_total_iter % self.params.log_interval == 0:
+ self.log_tensorboard()
+ self.last_log = time.time()
+ if self.n_total_iter % self.params.checkpoint_interval == 0:
+ self.save_checkpoint()
+
+ def log_tensorboard(self):
+ """
+ Log into tensorboard. Only by the master process.
+ """
+ if not self.is_master:
+ return
+
+ for param_name, param in self.student.named_parameters():
+ self.tensorboard.add_scalar(
+ tag="parameter_mean/" + param_name, scalar_value=param.data.mean(), global_step=self.n_total_iter
+ )
+ self.tensorboard.add_scalar(
+ tag="parameter_std/" + param_name, scalar_value=param.data.std(), global_step=self.n_total_iter
+ )
+ if param.grad is None:
+ continue
+ self.tensorboard.add_scalar(
+ tag="grad_mean/" + param_name, scalar_value=param.grad.data.mean(), global_step=self.n_total_iter
+ )
+ self.tensorboard.add_scalar(
+ tag="grad_std/" + param_name, scalar_value=param.grad.data.std(), global_step=self.n_total_iter
+ )
+
+ self.tensorboard.add_scalar(
+ tag="losses/cum_avg_loss_epoch",
+ scalar_value=self.total_loss_epoch / self.n_iter,
+ global_step=self.n_total_iter,
+ )
+ self.tensorboard.add_scalar(tag="losses/loss", scalar_value=self.last_loss, global_step=self.n_total_iter)
+ self.tensorboard.add_scalar(
+ tag="losses/loss_ce", scalar_value=self.last_loss_ce, global_step=self.n_total_iter
+ )
+ if self.alpha_mlm > 0.0:
+ self.tensorboard.add_scalar(
+ tag="losses/loss_mlm", scalar_value=self.last_loss_mlm, global_step=self.n_total_iter
+ )
+ if self.alpha_clm > 0.0:
+ self.tensorboard.add_scalar(
+ tag="losses/loss_clm", scalar_value=self.last_loss_clm, global_step=self.n_total_iter
+ )
+ if self.alpha_mse > 0.0:
+ self.tensorboard.add_scalar(
+ tag="losses/loss_mse", scalar_value=self.last_loss_mse, global_step=self.n_total_iter
+ )
+ if self.alpha_cos > 0.0:
+ self.tensorboard.add_scalar(
+ tag="losses/loss_cos", scalar_value=self.last_loss_cos, global_step=self.n_total_iter
+ )
+ self.tensorboard.add_scalar(
+ tag="learning_rate/lr", scalar_value=self.scheduler.get_lr()[0], global_step=self.n_total_iter
+ )
+
+ self.tensorboard.add_scalar(
+ tag="global/memory_usage",
+ scalar_value=psutil.virtual_memory()._asdict()["used"] / 1_000_000,
+ global_step=self.n_total_iter,
+ )
+ self.tensorboard.add_scalar(
+ tag="global/speed", scalar_value=time.time() - self.last_log, global_step=self.n_total_iter
+ )
+
+ def end_epoch(self):
+ """
+ Finally arrived at the end of epoch (full pass on dataset).
+ Do some tensorboard logging and checkpoint saving.
+ """
+ logger.info(f"{self.n_sequences_epoch} sequences have been trained during this epoch.")
+
+ if self.is_master:
+ self.save_checkpoint(checkpoint_name=f"model_epoch_{self.epoch}.pth")
+ self.tensorboard.add_scalar(
+ tag="epoch/loss", scalar_value=self.total_loss_epoch / self.n_iter, global_step=self.epoch
+ )
+
+ self.epoch += 1
+ self.n_sequences_epoch = 0
+ self.n_iter = 0
+ self.total_loss_epoch = 0
+
+ def save_checkpoint(self, checkpoint_name: str = "checkpoint.pth"):
+ """
+ Save the current state. Only by the master process.
+ """
+ if not self.is_master:
+ return
+ mdl_to_save = self.student.module if hasattr(self.student, "module") else self.student
+ mdl_to_save.config.save_pretrained(self.dump_path)
+ state_dict = mdl_to_save.state_dict()
+ torch.save(state_dict, os.path.join(self.dump_path, checkpoint_name))
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/grouped_batch_sampler.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/grouped_batch_sampler.py
new file mode 100644
index 0000000000000000000000000000000000000000..e25def738a8483ce74ea179a6211e9b429965e6e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/grouped_batch_sampler.py
@@ -0,0 +1,108 @@
+# coding=utf-8
+# Copyright 2019-present, the HuggingFace Inc. team and Facebook, Inc.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Adapted from PyTorch Vision (https://github.com/pytorch/vision/blob/master/references/detection/group_by_aspect_ratio.py)"""
+
+import bisect
+import copy
+from collections import defaultdict
+
+import numpy as np
+from torch.utils.data import BatchSampler, Sampler
+
+from utils import logger
+
+
+def _quantize(x, bins):
+ bins = copy.deepcopy(bins)
+ bins = sorted(bins)
+ quantized = [bisect.bisect_right(bins, y) for y in x]
+ return quantized
+
+
+def create_lengths_groups(lengths, k=0):
+ bins = np.arange(start=3, stop=k, step=4).tolist() if k > 0 else [10]
+ groups = _quantize(lengths, bins)
+ # count number of elements per group
+ counts = np.unique(groups, return_counts=True)[1]
+ fbins = [0] + bins + [np.inf]
+ logger.info("Using {} as bins for aspect lengths quantization".format(fbins))
+ logger.info("Count of instances per bin: {}".format(counts))
+ return groups
+
+
+class GroupedBatchSampler(BatchSampler):
+ """
+ Wraps another sampler to yield a mini-batch of indices.
+ It enforces that the batch only contain elements from the same group.
+ It also tries to provide mini-batches which follows an ordering which is
+ as close as possible to the ordering from the original sampler.
+ Arguments:
+ sampler (Sampler): Base sampler.
+ group_ids (list[int]): If the sampler produces indices in range [0, N),
+ `group_ids` must be a list of `N` ints which contains the group id of each sample.
+ The group ids must be a continuous set of integers starting from
+ 0, i.e. they must be in the range [0, num_groups).
+ batch_size (int): Size of mini-batch.
+ """
+
+ def __init__(self, sampler, group_ids, batch_size):
+ if not isinstance(sampler, Sampler):
+ raise TypeError(
+ "sampler should be an instance of torch.utils.data.Sampler, but got sampler={}".format(sampler)
+ )
+ self.sampler = sampler
+ self.group_ids = group_ids
+ self.batch_size = batch_size
+
+ def __iter__(self):
+ buffer_per_group = defaultdict(list)
+ samples_per_group = defaultdict(list)
+
+ num_batches = 0
+ for idx in self.sampler:
+ group_id = self.group_ids[idx]
+ buffer_per_group[group_id].append(idx)
+ samples_per_group[group_id].append(idx)
+ if len(buffer_per_group[group_id]) == self.batch_size:
+ yield buffer_per_group[group_id] # TODO
+ num_batches += 1
+ del buffer_per_group[group_id]
+ assert len(buffer_per_group[group_id]) < self.batch_size
+
+ # now we have run out of elements that satisfy
+ # the group criteria, let's return the remaining
+ # elements so that the size of the sampler is
+ # deterministic
+ expected_num_batches = len(self)
+ num_remaining = expected_num_batches - num_batches
+ if num_remaining > 0:
+ # for the remaining batches, group the batches by similar lengths
+ batch_idx = []
+ for group_id, idxs in sorted(buffer_per_group.items(), key=lambda x: x[0]):
+ batch_idx.extend(idxs)
+ if len(batch_idx) >= self.batch_size:
+ yield batch_idx[: self.batch_size]
+ batch_idx = batch_idx[self.batch_size :]
+ num_remaining -= 1
+ if len(batch_idx) > 0:
+ yield batch_idx
+ num_remaining -= 1
+ assert num_remaining == 0
+
+ def __len__(self):
+ """
+ Return the number of mini-batches rather than the number of samples.
+ """
+ return (len(self.sampler) + self.batch_size - 1) // self.batch_size
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/lm_seqs_dataset.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/lm_seqs_dataset.py
new file mode 100644
index 0000000000000000000000000000000000000000..647c8f464f7eb807cd859a21f33f29bcbb64b502
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/lm_seqs_dataset.py
@@ -0,0 +1,167 @@
+# coding=utf-8
+# Copyright 2019-present, the HuggingFace Inc. team and Facebook, Inc.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Dataset to distilled models
+adapted in part from Facebook, Inc XLM model (https://github.com/facebookresearch/XLM)
+"""
+
+import numpy as np
+import torch
+from torch.utils.data import Dataset
+
+from utils import logger
+
+
+class LmSeqsDataset(Dataset):
+ """Custom Dataset wrapping language modeling sequences.
+
+ Each sample will be retrieved by indexing the list of token_ids and their corresponding lengths.
+
+ Input:
+ ------
+ params: `NameSpace` parameters
+ data: `List[np.array[int]]
+ """
+
+ def __init__(self, params, data):
+ self.params = params
+
+ self.token_ids = np.array(data)
+ self.lengths = np.array([len(t) for t in data])
+
+ self.check()
+ self.remove_long_sequences()
+ self.remove_empty_sequences()
+ self.remove_unknown_sequences()
+ self.check()
+ self.print_statistics()
+
+ def __getitem__(self, index):
+ return (self.token_ids[index], self.lengths[index])
+
+ def __len__(self):
+ return len(self.lengths)
+
+ def check(self):
+ """
+ Some sanity checks
+ """
+ assert len(self.token_ids) == len(self.lengths)
+ assert all(self.lengths[i] == len(self.token_ids[i]) for i in range(len(self.lengths)))
+
+ def remove_long_sequences(self):
+ """
+ Sequences that are too long are split by chunk of max_model_input_size.
+ """
+ max_len = self.params.max_model_input_size
+ indices = self.lengths > max_len
+ logger.info(f"Splitting {sum(indices)} too long sequences.")
+
+ def divide_chunks(l, n):
+ return [l[i : i + n] for i in range(0, len(l), n)]
+
+ new_tok_ids = []
+ new_lengths = []
+ if self.params.mlm:
+ cls_id, sep_id = self.params.special_tok_ids["cls_token"], self.params.special_tok_ids["sep_token"]
+ else:
+ cls_id, sep_id = self.params.special_tok_ids["bos_token"], self.params.special_tok_ids["eos_token"]
+
+ for seq_, len_ in zip(self.token_ids, self.lengths):
+ assert (seq_[0] == cls_id) and (seq_[-1] == sep_id), seq_
+ if len_ <= max_len:
+ new_tok_ids.append(seq_)
+ new_lengths.append(len_)
+ else:
+ sub_seqs = []
+ for sub_s in divide_chunks(seq_, max_len - 2):
+ if sub_s[0] != cls_id:
+ sub_s = np.insert(sub_s, 0, cls_id)
+ if sub_s[-1] != sep_id:
+ sub_s = np.insert(sub_s, len(sub_s), sep_id)
+ assert len(sub_s) <= max_len
+ assert (sub_s[0] == cls_id) and (sub_s[-1] == sep_id), sub_s
+ sub_seqs.append(sub_s)
+
+ new_tok_ids.extend(sub_seqs)
+ new_lengths.extend([len(l) for l in sub_seqs])
+
+ self.token_ids = np.array(new_tok_ids)
+ self.lengths = np.array(new_lengths)
+
+ def remove_empty_sequences(self):
+ """
+ Too short sequences are simply removed. This could be tuned.
+ """
+ init_size = len(self)
+ indices = self.lengths > 11
+ self.token_ids = self.token_ids[indices]
+ self.lengths = self.lengths[indices]
+ new_size = len(self)
+ logger.info(f"Remove {init_size - new_size} too short (<=11 tokens) sequences.")
+
+ def remove_unknown_sequences(self):
+ """
+ Remove sequences with a (too) high level of unknown tokens.
+ """
+ if "unk_token" not in self.params.special_tok_ids:
+ return
+ else:
+ unk_token_id = self.params.special_tok_ids["unk_token"]
+ init_size = len(self)
+ unk_occs = np.array([np.count_nonzero(a == unk_token_id) for a in self.token_ids])
+ indices = (unk_occs / self.lengths) < 0.5
+ self.token_ids = self.token_ids[indices]
+ self.lengths = self.lengths[indices]
+ new_size = len(self)
+ logger.info(f"Remove {init_size - new_size} sequences with a high level of unknown tokens (50%).")
+
+ def print_statistics(self):
+ """
+ Print some statistics on the corpus. Only the master process.
+ """
+ if not self.params.is_master:
+ return
+ logger.info(f"{len(self)} sequences")
+ # data_len = sum(self.lengths)
+ # nb_unique_tokens = len(Counter(list(chain(*self.token_ids))))
+ # logger.info(f'{data_len} tokens ({nb_unique_tokens} unique)')
+
+ # unk_idx = self.params.special_tok_ids['unk_token']
+ # nb_unknown = sum([(t==unk_idx).sum() for t in self.token_ids])
+ # logger.info(f'{nb_unknown} unknown tokens (covering {100*nb_unknown/data_len:.2f}% of the data)')
+
+ def batch_sequences(self, batch):
+ """
+ Do the padding and transform into torch.tensor.
+ """
+ token_ids = [t[0] for t in batch]
+ lengths = [t[1] for t in batch]
+ assert len(token_ids) == len(lengths)
+
+ # Max for paddings
+ max_seq_len_ = max(lengths)
+
+ # Pad token ids
+ if self.params.mlm:
+ pad_idx = self.params.special_tok_ids["pad_token"]
+ else:
+ pad_idx = self.params.special_tok_ids["unk_token"]
+ tk_ = [list(t.astype(int)) + [pad_idx] * (max_seq_len_ - len(t)) for t in token_ids]
+ assert len(tk_) == len(token_ids)
+ assert all(len(t) == max_seq_len_ for t in tk_)
+
+ tk_t = torch.tensor(tk_) # (bs, max_seq_len_)
+ lg_t = torch.tensor(lengths) # (bs)
+ return tk_t, lg_t
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..4a2ed783a7c984174a9576f62a254066f03d7a0a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/requirements.txt
@@ -0,0 +1,7 @@
+transformers
+
+gitpython==3.1.41
+tensorboard>=1.14.0
+tensorboardX==1.8
+psutil==5.6.6
+scipy>=1.4.1
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/run_squad_w_distillation.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/run_squad_w_distillation.py
new file mode 100644
index 0000000000000000000000000000000000000000..a1150f6b437e5976c4f1b55f107d5d7b92a08d99
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/run_squad_w_distillation.py
@@ -0,0 +1,877 @@
+# coding=utf-8
+# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""This is the exact same script as `examples/question-answering/run_squad.py` (as of 2020, January 8th) with an additional and optional step of distillation."""
+
+import argparse
+import glob
+import logging
+import os
+import random
+import timeit
+
+import numpy as np
+import torch
+from torch import nn
+from torch.utils.data import DataLoader, RandomSampler, SequentialSampler
+from torch.utils.data.distributed import DistributedSampler
+from tqdm import tqdm, trange
+
+import transformers
+from transformers import (
+ WEIGHTS_NAME,
+ AdamW,
+ BertConfig,
+ BertForQuestionAnswering,
+ BertTokenizer,
+ DistilBertConfig,
+ DistilBertForQuestionAnswering,
+ DistilBertTokenizer,
+ RobertaConfig,
+ RobertaForQuestionAnswering,
+ RobertaTokenizer,
+ XLMConfig,
+ XLMForQuestionAnswering,
+ XLMTokenizer,
+ XLNetConfig,
+ XLNetForQuestionAnswering,
+ XLNetTokenizer,
+ get_linear_schedule_with_warmup,
+ squad_convert_examples_to_features,
+)
+from transformers.data.metrics.squad_metrics import (
+ compute_predictions_log_probs,
+ compute_predictions_logits,
+ squad_evaluate,
+)
+from transformers.data.processors.squad import SquadResult, SquadV1Processor, SquadV2Processor
+from transformers.trainer_utils import is_main_process
+
+
+try:
+ from torch.utils.tensorboard import SummaryWriter
+except ImportError:
+ from tensorboardX import SummaryWriter
+
+
+logger = logging.getLogger(__name__)
+
+
+MODEL_CLASSES = {
+ "bert": (BertConfig, BertForQuestionAnswering, BertTokenizer),
+ "xlnet": (XLNetConfig, XLNetForQuestionAnswering, XLNetTokenizer),
+ "xlm": (XLMConfig, XLMForQuestionAnswering, XLMTokenizer),
+ "distilbert": (DistilBertConfig, DistilBertForQuestionAnswering, DistilBertTokenizer),
+ "roberta": (RobertaConfig, RobertaForQuestionAnswering, RobertaTokenizer),
+}
+
+
+def set_seed(args):
+ random.seed(args.seed)
+ np.random.seed(args.seed)
+ torch.manual_seed(args.seed)
+ if args.n_gpu > 0:
+ torch.cuda.manual_seed_all(args.seed)
+
+
+def to_list(tensor):
+ return tensor.detach().cpu().tolist()
+
+
+def train(args, train_dataset, model, tokenizer, teacher=None):
+ """Train the model"""
+ if args.local_rank in [-1, 0]:
+ tb_writer = SummaryWriter()
+
+ args.train_batch_size = args.per_gpu_train_batch_size * max(1, args.n_gpu)
+ train_sampler = RandomSampler(train_dataset) if args.local_rank == -1 else DistributedSampler(train_dataset)
+ train_dataloader = DataLoader(train_dataset, sampler=train_sampler, batch_size=args.train_batch_size)
+
+ if args.max_steps > 0:
+ t_total = args.max_steps
+ args.num_train_epochs = args.max_steps // (len(train_dataloader) // args.gradient_accumulation_steps) + 1
+ else:
+ t_total = len(train_dataloader) // args.gradient_accumulation_steps * args.num_train_epochs
+
+ # Prepare optimizer and schedule (linear warmup and decay)
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": args.weight_decay,
+ },
+ {"params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)], "weight_decay": 0.0},
+ ]
+ optimizer = AdamW(optimizer_grouped_parameters, lr=args.learning_rate, eps=args.adam_epsilon)
+ scheduler = get_linear_schedule_with_warmup(
+ optimizer, num_warmup_steps=args.warmup_steps, num_training_steps=t_total
+ )
+
+ # Check if saved optimizer or scheduler states exist
+ if os.path.isfile(os.path.join(args.model_name_or_path, "optimizer.pt")) and os.path.isfile(
+ os.path.join(args.model_name_or_path, "scheduler.pt")
+ ):
+ # Load in optimizer and scheduler states
+ optimizer.load_state_dict(torch.load(os.path.join(args.model_name_or_path, "optimizer.pt")))
+ scheduler.load_state_dict(torch.load(os.path.join(args.model_name_or_path, "scheduler.pt")))
+
+ if args.fp16:
+ try:
+ from apex import amp
+ except ImportError:
+ raise ImportError("Please install apex from https://www.github.com/nvidia/apex to use fp16 training.")
+
+ model, optimizer = amp.initialize(model, optimizer, opt_level=args.fp16_opt_level)
+
+ # multi-gpu training (should be after apex fp16 initialization)
+ if args.n_gpu > 1:
+ model = nn.DataParallel(model)
+
+ # Distributed training (should be after apex fp16 initialization)
+ if args.local_rank != -1:
+ model = nn.parallel.DistributedDataParallel(
+ model, device_ids=[args.local_rank], output_device=args.local_rank, find_unused_parameters=True
+ )
+
+ # Train!
+ logger.info("***** Running training *****")
+ logger.info(" Num examples = %d", len(train_dataset))
+ logger.info(" Num Epochs = %d", args.num_train_epochs)
+ logger.info(" Instantaneous batch size per GPU = %d", args.per_gpu_train_batch_size)
+ logger.info(
+ " Total train batch size (w. parallel, distributed & accumulation) = %d",
+ args.train_batch_size
+ * args.gradient_accumulation_steps
+ * (torch.distributed.get_world_size() if args.local_rank != -1 else 1),
+ )
+ logger.info(" Gradient Accumulation steps = %d", args.gradient_accumulation_steps)
+ logger.info(" Total optimization steps = %d", t_total)
+
+ global_step = 1
+ epochs_trained = 0
+ steps_trained_in_current_epoch = 0
+ # Check if continuing training from a checkpoint
+ if os.path.exists(args.model_name_or_path):
+ try:
+ # set global_step to global_step of last saved checkpoint from model path
+ checkpoint_suffix = args.model_name_or_path.split("-")[-1].split("/")[0]
+ global_step = int(checkpoint_suffix)
+ epochs_trained = global_step // (len(train_dataloader) // args.gradient_accumulation_steps)
+ steps_trained_in_current_epoch = global_step % (len(train_dataloader) // args.gradient_accumulation_steps)
+
+ logger.info(" Continuing training from checkpoint, will skip to saved global_step")
+ logger.info(" Continuing training from epoch %d", epochs_trained)
+ logger.info(" Continuing training from global step %d", global_step)
+ logger.info(" Will skip the first %d steps in the first epoch", steps_trained_in_current_epoch)
+ except ValueError:
+ logger.info(" Starting fine-tuning.")
+
+ tr_loss, logging_loss = 0.0, 0.0
+ model.zero_grad()
+ train_iterator = trange(
+ epochs_trained, int(args.num_train_epochs), desc="Epoch", disable=args.local_rank not in [-1, 0]
+ )
+ # Added here for reproducibility
+ set_seed(args)
+
+ for _ in train_iterator:
+ epoch_iterator = tqdm(train_dataloader, desc="Iteration", disable=args.local_rank not in [-1, 0])
+ for step, batch in enumerate(epoch_iterator):
+ # Skip past any already trained steps if resuming training
+ if steps_trained_in_current_epoch > 0:
+ steps_trained_in_current_epoch -= 1
+ continue
+
+ model.train()
+ if teacher is not None:
+ teacher.eval()
+ batch = tuple(t.to(args.device) for t in batch)
+
+ inputs = {
+ "input_ids": batch[0],
+ "attention_mask": batch[1],
+ "start_positions": batch[3],
+ "end_positions": batch[4],
+ }
+ if args.model_type != "distilbert":
+ inputs["token_type_ids"] = None if args.model_type == "xlm" else batch[2]
+ if args.model_type in ["xlnet", "xlm"]:
+ inputs.update({"cls_index": batch[5], "p_mask": batch[6]})
+ if args.version_2_with_negative:
+ inputs.update({"is_impossible": batch[7]})
+ outputs = model(**inputs)
+ loss, start_logits_stu, end_logits_stu = outputs
+
+ # Distillation loss
+ if teacher is not None:
+ if "token_type_ids" not in inputs:
+ inputs["token_type_ids"] = None if args.teacher_type == "xlm" else batch[2]
+ with torch.no_grad():
+ start_logits_tea, end_logits_tea = teacher(
+ input_ids=inputs["input_ids"],
+ token_type_ids=inputs["token_type_ids"],
+ attention_mask=inputs["attention_mask"],
+ )
+ assert start_logits_tea.size() == start_logits_stu.size()
+ assert end_logits_tea.size() == end_logits_stu.size()
+
+ loss_fct = nn.KLDivLoss(reduction="batchmean")
+ loss_start = loss_fct(
+ nn.functional.log_softmax(start_logits_stu / args.temperature, dim=-1),
+ nn.functional.softmax(start_logits_tea / args.temperature, dim=-1),
+ ) * (args.temperature**2)
+ loss_end = loss_fct(
+ nn.functional.log_softmax(end_logits_stu / args.temperature, dim=-1),
+ nn.functional.softmax(end_logits_tea / args.temperature, dim=-1),
+ ) * (args.temperature**2)
+ loss_ce = (loss_start + loss_end) / 2.0
+
+ loss = args.alpha_ce * loss_ce + args.alpha_squad * loss
+
+ if args.n_gpu > 1:
+ loss = loss.mean() # mean() to average on multi-gpu parallel (not distributed) training
+ if args.gradient_accumulation_steps > 1:
+ loss = loss / args.gradient_accumulation_steps
+
+ if args.fp16:
+ with amp.scale_loss(loss, optimizer) as scaled_loss:
+ scaled_loss.backward()
+ else:
+ loss.backward()
+
+ tr_loss += loss.item()
+ if (step + 1) % args.gradient_accumulation_steps == 0:
+ if args.fp16:
+ nn.utils.clip_grad_norm_(amp.master_params(optimizer), args.max_grad_norm)
+ else:
+ nn.utils.clip_grad_norm_(model.parameters(), args.max_grad_norm)
+
+ optimizer.step()
+ scheduler.step() # Update learning rate schedule
+ model.zero_grad()
+ global_step += 1
+
+ # Log metrics
+ if args.local_rank in [-1, 0] and args.logging_steps > 0 and global_step % args.logging_steps == 0:
+ # Only evaluate when single GPU otherwise metrics may not average well
+ if args.local_rank == -1 and args.evaluate_during_training:
+ results = evaluate(args, model, tokenizer)
+ for key, value in results.items():
+ tb_writer.add_scalar("eval_{}".format(key), value, global_step)
+ tb_writer.add_scalar("lr", scheduler.get_lr()[0], global_step)
+ tb_writer.add_scalar("loss", (tr_loss - logging_loss) / args.logging_steps, global_step)
+ logging_loss = tr_loss
+
+ if args.local_rank in [-1, 0] and args.save_steps > 0 and global_step % args.save_steps == 0:
+ # Save model checkpoint
+ output_dir = os.path.join(args.output_dir, "checkpoint-{}".format(global_step))
+ if not os.path.exists(output_dir):
+ os.makedirs(output_dir)
+ model_to_save = (
+ model.module if hasattr(model, "module") else model
+ ) # Take care of distributed/parallel training
+ model_to_save.save_pretrained(output_dir)
+ tokenizer.save_pretrained(output_dir)
+
+ torch.save(args, os.path.join(output_dir, "training_args.bin"))
+ logger.info("Saving model checkpoint to %s", output_dir)
+
+ torch.save(optimizer.state_dict(), os.path.join(output_dir, "optimizer.pt"))
+ torch.save(scheduler.state_dict(), os.path.join(output_dir, "scheduler.pt"))
+ logger.info("Saving optimizer and scheduler states to %s", output_dir)
+
+ if args.max_steps > 0 and global_step > args.max_steps:
+ epoch_iterator.close()
+ break
+ if args.max_steps > 0 and global_step > args.max_steps:
+ train_iterator.close()
+ break
+
+ if args.local_rank in [-1, 0]:
+ tb_writer.close()
+
+ return global_step, tr_loss / global_step
+
+
+def evaluate(args, model, tokenizer, prefix=""):
+ dataset, examples, features = load_and_cache_examples(args, tokenizer, evaluate=True, output_examples=True)
+
+ if not os.path.exists(args.output_dir) and args.local_rank in [-1, 0]:
+ os.makedirs(args.output_dir)
+
+ args.eval_batch_size = args.per_gpu_eval_batch_size * max(1, args.n_gpu)
+
+ # Note that DistributedSampler samples randomly
+ eval_sampler = SequentialSampler(dataset)
+ eval_dataloader = DataLoader(dataset, sampler=eval_sampler, batch_size=args.eval_batch_size)
+
+ # multi-gpu evaluate
+ if args.n_gpu > 1 and not isinstance(model, nn.DataParallel):
+ model = nn.DataParallel(model)
+
+ # Eval!
+ logger.info("***** Running evaluation {} *****".format(prefix))
+ logger.info(" Num examples = %d", len(dataset))
+ logger.info(" Batch size = %d", args.eval_batch_size)
+
+ all_results = []
+ start_time = timeit.default_timer()
+
+ for batch in tqdm(eval_dataloader, desc="Evaluating"):
+ model.eval()
+ batch = tuple(t.to(args.device) for t in batch)
+
+ with torch.no_grad():
+ inputs = {"input_ids": batch[0], "attention_mask": batch[1]}
+ if args.model_type != "distilbert":
+ inputs["token_type_ids"] = None if args.model_type == "xlm" else batch[2] # XLM don't use segment_ids
+ example_indices = batch[3]
+ if args.model_type in ["xlnet", "xlm"]:
+ inputs.update({"cls_index": batch[4], "p_mask": batch[5]})
+
+ outputs = model(**inputs)
+
+ for i, example_index in enumerate(example_indices):
+ eval_feature = features[example_index.item()]
+ unique_id = int(eval_feature.unique_id)
+
+ output = [to_list(output[i]) for output in outputs]
+
+ # Some models (XLNet, XLM) use 5 arguments for their predictions, while the other "simpler"
+ # models only use two.
+ if len(output) >= 5:
+ start_logits = output[0]
+ start_top_index = output[1]
+ end_logits = output[2]
+ end_top_index = output[3]
+ cls_logits = output[4]
+
+ result = SquadResult(
+ unique_id,
+ start_logits,
+ end_logits,
+ start_top_index=start_top_index,
+ end_top_index=end_top_index,
+ cls_logits=cls_logits,
+ )
+
+ else:
+ start_logits, end_logits = output
+ result = SquadResult(unique_id, start_logits, end_logits)
+
+ all_results.append(result)
+
+ evalTime = timeit.default_timer() - start_time
+ logger.info(" Evaluation done in total %f secs (%f sec per example)", evalTime, evalTime / len(dataset))
+
+ # Compute predictions
+ output_prediction_file = os.path.join(args.output_dir, "predictions_{}.json".format(prefix))
+ output_nbest_file = os.path.join(args.output_dir, "nbest_predictions_{}.json".format(prefix))
+
+ if args.version_2_with_negative:
+ output_null_log_odds_file = os.path.join(args.output_dir, "null_odds_{}.json".format(prefix))
+ else:
+ output_null_log_odds_file = None
+
+ if args.model_type in ["xlnet", "xlm"]:
+ # XLNet uses a more complex post-processing procedure
+ predictions = compute_predictions_log_probs(
+ examples,
+ features,
+ all_results,
+ args.n_best_size,
+ args.max_answer_length,
+ output_prediction_file,
+ output_nbest_file,
+ output_null_log_odds_file,
+ model.config.start_n_top,
+ model.config.end_n_top,
+ args.version_2_with_negative,
+ tokenizer,
+ args.verbose_logging,
+ )
+ else:
+ predictions = compute_predictions_logits(
+ examples,
+ features,
+ all_results,
+ args.n_best_size,
+ args.max_answer_length,
+ args.do_lower_case,
+ output_prediction_file,
+ output_nbest_file,
+ output_null_log_odds_file,
+ args.verbose_logging,
+ args.version_2_with_negative,
+ args.null_score_diff_threshold,
+ tokenizer,
+ )
+
+ # Compute the F1 and exact scores.
+ results = squad_evaluate(examples, predictions)
+ return results
+
+
+def load_and_cache_examples(args, tokenizer, evaluate=False, output_examples=False):
+ if args.local_rank not in [-1, 0] and not evaluate:
+ # Make sure only the first process in distributed training process the dataset, and the others will use the cache
+ torch.distributed.barrier()
+
+ # Load data features from cache or dataset file
+ input_file = args.predict_file if evaluate else args.train_file
+ cached_features_file = os.path.join(
+ os.path.dirname(input_file),
+ "cached_distillation_{}_{}_{}".format(
+ "dev" if evaluate else "train",
+ list(filter(None, args.model_name_or_path.split("/"))).pop(),
+ str(args.max_seq_length),
+ ),
+ )
+ if os.path.exists(cached_features_file) and not args.overwrite_cache:
+ logger.info("Loading features from cached file %s", cached_features_file)
+ features_and_dataset = torch.load(cached_features_file)
+
+ try:
+ features, dataset, examples = (
+ features_and_dataset["features"],
+ features_and_dataset["dataset"],
+ features_and_dataset["examples"],
+ )
+ except KeyError:
+ raise DeprecationWarning(
+ "You seem to be loading features from an older version of this script please delete the "
+ "file %s in order for it to be created again" % cached_features_file
+ )
+ else:
+ logger.info("Creating features from dataset file at %s", input_file)
+ processor = SquadV2Processor() if args.version_2_with_negative else SquadV1Processor()
+ if evaluate:
+ examples = processor.get_dev_examples(args.data_dir, filename=args.predict_file)
+ else:
+ examples = processor.get_train_examples(args.data_dir, filename=args.train_file)
+
+ features, dataset = squad_convert_examples_to_features(
+ examples=examples,
+ tokenizer=tokenizer,
+ max_seq_length=args.max_seq_length,
+ doc_stride=args.doc_stride,
+ max_query_length=args.max_query_length,
+ is_training=not evaluate,
+ return_dataset="pt",
+ threads=args.threads,
+ )
+
+ if args.local_rank in [-1, 0]:
+ logger.info("Saving features into cached file %s", cached_features_file)
+ torch.save({"features": features, "dataset": dataset, "examples": examples}, cached_features_file)
+
+ if args.local_rank == 0 and not evaluate:
+ # Make sure only the first process in distributed training process the dataset, and the others will use the cache
+ torch.distributed.barrier()
+
+ if output_examples:
+ return dataset, examples, features
+ return dataset
+
+
+def main():
+ parser = argparse.ArgumentParser()
+
+ # Required parameters
+ parser.add_argument(
+ "--model_type",
+ default=None,
+ type=str,
+ required=True,
+ help="Model type selected in the list: " + ", ".join(MODEL_CLASSES.keys()),
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ default=None,
+ type=str,
+ required=True,
+ help="Path to pretrained model or model identifier from huggingface.co/models",
+ )
+ parser.add_argument(
+ "--output_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The output directory where the model checkpoints and predictions will be written.",
+ )
+
+ # Distillation parameters (optional)
+ parser.add_argument(
+ "--teacher_type",
+ default=None,
+ type=str,
+ help=(
+ "Teacher type. Teacher tokenizer and student (model) tokenizer must output the same tokenization. Only for"
+ " distillation."
+ ),
+ )
+ parser.add_argument(
+ "--teacher_name_or_path",
+ default=None,
+ type=str,
+ help="Path to the already SQuAD fine-tuned teacher model. Only for distillation.",
+ )
+ parser.add_argument(
+ "--alpha_ce", default=0.5, type=float, help="Distillation loss linear weight. Only for distillation."
+ )
+ parser.add_argument(
+ "--alpha_squad", default=0.5, type=float, help="True SQuAD loss linear weight. Only for distillation."
+ )
+ parser.add_argument(
+ "--temperature", default=2.0, type=float, help="Distillation temperature. Only for distillation."
+ )
+
+ # Other parameters
+ parser.add_argument(
+ "--data_dir",
+ default=None,
+ type=str,
+ help="The input data dir. Should contain the .json files for the task."
+ + "If no data dir or train/predict files are specified, will run with tensorflow_datasets.",
+ )
+ parser.add_argument(
+ "--train_file",
+ default=None,
+ type=str,
+ help="The input training file. If a data dir is specified, will look for the file there"
+ + "If no data dir or train/predict files are specified, will run with tensorflow_datasets.",
+ )
+ parser.add_argument(
+ "--predict_file",
+ default=None,
+ type=str,
+ help="The input evaluation file. If a data dir is specified, will look for the file there"
+ + "If no data dir or train/predict files are specified, will run with tensorflow_datasets.",
+ )
+ parser.add_argument(
+ "--config_name", default="", type=str, help="Pretrained config name or path if not the same as model_name"
+ )
+ parser.add_argument(
+ "--tokenizer_name",
+ default="",
+ type=str,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument(
+ "--cache_dir",
+ default="",
+ type=str,
+ help="Where do you want to store the pre-trained models downloaded from huggingface.co",
+ )
+
+ parser.add_argument(
+ "--version_2_with_negative",
+ action="store_true",
+ help="If true, the SQuAD examples contain some that do not have an answer.",
+ )
+ parser.add_argument(
+ "--null_score_diff_threshold",
+ type=float,
+ default=0.0,
+ help="If null_score - best_non_null is greater than the threshold predict null.",
+ )
+
+ parser.add_argument(
+ "--max_seq_length",
+ default=384,
+ type=int,
+ help=(
+ "The maximum total input sequence length after WordPiece tokenization. Sequences "
+ "longer than this will be truncated, and sequences shorter than this will be padded."
+ ),
+ )
+ parser.add_argument(
+ "--doc_stride",
+ default=128,
+ type=int,
+ help="When splitting up a long document into chunks, how much stride to take between chunks.",
+ )
+ parser.add_argument(
+ "--max_query_length",
+ default=64,
+ type=int,
+ help=(
+ "The maximum number of tokens for the question. Questions longer than this will "
+ "be truncated to this length."
+ ),
+ )
+ parser.add_argument("--do_train", action="store_true", help="Whether to run training.")
+ parser.add_argument("--do_eval", action="store_true", help="Whether to run eval on the dev set.")
+ parser.add_argument(
+ "--evaluate_during_training", action="store_true", help="Rul evaluation during training at each logging step."
+ )
+ parser.add_argument(
+ "--do_lower_case", action="store_true", help="Set this flag if you are using an uncased model."
+ )
+
+ parser.add_argument("--per_gpu_train_batch_size", default=8, type=int, help="Batch size per GPU/CPU for training.")
+ parser.add_argument(
+ "--per_gpu_eval_batch_size", default=8, type=int, help="Batch size per GPU/CPU for evaluation."
+ )
+ parser.add_argument("--learning_rate", default=5e-5, type=float, help="The initial learning rate for Adam.")
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument("--weight_decay", default=0.0, type=float, help="Weight decay if we apply some.")
+ parser.add_argument("--adam_epsilon", default=1e-8, type=float, help="Epsilon for Adam optimizer.")
+ parser.add_argument("--max_grad_norm", default=1.0, type=float, help="Max gradient norm.")
+ parser.add_argument(
+ "--num_train_epochs", default=3.0, type=float, help="Total number of training epochs to perform."
+ )
+ parser.add_argument(
+ "--max_steps",
+ default=-1,
+ type=int,
+ help="If > 0: set total number of training steps to perform. Override num_train_epochs.",
+ )
+ parser.add_argument("--warmup_steps", default=0, type=int, help="Linear warmup over warmup_steps.")
+ parser.add_argument(
+ "--n_best_size",
+ default=20,
+ type=int,
+ help="The total number of n-best predictions to generate in the nbest_predictions.json output file.",
+ )
+ parser.add_argument(
+ "--max_answer_length",
+ default=30,
+ type=int,
+ help=(
+ "The maximum length of an answer that can be generated. This is needed because the start "
+ "and end predictions are not conditioned on one another."
+ ),
+ )
+ parser.add_argument(
+ "--verbose_logging",
+ action="store_true",
+ help=(
+ "If true, all of the warnings related to data processing will be printed. "
+ "A number of warnings are expected for a normal SQuAD evaluation."
+ ),
+ )
+
+ parser.add_argument("--logging_steps", type=int, default=50, help="Log every X updates steps.")
+ parser.add_argument("--save_steps", type=int, default=50, help="Save checkpoint every X updates steps.")
+ parser.add_argument(
+ "--eval_all_checkpoints",
+ action="store_true",
+ help="Evaluate all checkpoints starting with the same prefix as model_name ending and ending with step number",
+ )
+ parser.add_argument("--no_cuda", action="store_true", help="Whether not to use CUDA when available")
+ parser.add_argument(
+ "--overwrite_output_dir", action="store_true", help="Overwrite the content of the output directory"
+ )
+ parser.add_argument(
+ "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
+ )
+ parser.add_argument("--seed", type=int, default=42, help="random seed for initialization")
+
+ parser.add_argument("--local_rank", type=int, default=-1, help="local_rank for distributed training on gpus")
+ parser.add_argument(
+ "--fp16",
+ action="store_true",
+ help="Whether to use 16-bit (mixed) precision (through NVIDIA apex) instead of 32-bit",
+ )
+ parser.add_argument(
+ "--fp16_opt_level",
+ type=str,
+ default="O1",
+ help=(
+ "For fp16: Apex AMP optimization level selected in ['O0', 'O1', 'O2', and 'O3']. "
+ "See details at https://nvidia.github.io/apex/amp.html"
+ ),
+ )
+ parser.add_argument("--server_ip", type=str, default="", help="Can be used for distant debugging.")
+ parser.add_argument("--server_port", type=str, default="", help="Can be used for distant debugging.")
+
+ parser.add_argument("--threads", type=int, default=1, help="multiple threads for converting example to features")
+ args = parser.parse_args()
+
+ if (
+ os.path.exists(args.output_dir)
+ and os.listdir(args.output_dir)
+ and args.do_train
+ and not args.overwrite_output_dir
+ ):
+ raise ValueError(
+ "Output directory ({}) already exists and is not empty. Use --overwrite_output_dir to overcome.".format(
+ args.output_dir
+ )
+ )
+
+ # Setup distant debugging if needed
+ if args.server_ip and args.server_port:
+ # Distant debugging - see https://code.visualstudio.com/docs/python/debugging#_attach-to-a-local-script
+ import ptvsd
+
+ print("Waiting for debugger attach")
+ ptvsd.enable_attach(address=(args.server_ip, args.server_port), redirect_output=True)
+ ptvsd.wait_for_attach()
+
+ # Setup CUDA, GPU & distributed training
+ if args.local_rank == -1 or args.no_cuda:
+ device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
+ args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
+ else: # Initializes the distributed backend which will take care of synchronizing nodes/GPUs
+ torch.cuda.set_device(args.local_rank)
+ device = torch.device("cuda", args.local_rank)
+ torch.distributed.init_process_group(backend="nccl")
+ args.n_gpu = 1
+ args.device = device
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO if args.local_rank in [-1, 0] else logging.WARN,
+ )
+ logger.warning(
+ "Process rank: %s, device: %s, n_gpu: %s, distributed training: %s, 16-bits training: %s",
+ args.local_rank,
+ device,
+ args.n_gpu,
+ bool(args.local_rank != -1),
+ args.fp16,
+ )
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ if is_main_process(args.local_rank):
+ transformers.utils.logging.set_verbosity_info()
+ transformers.utils.logging.enable_default_handler()
+ transformers.utils.logging.enable_explicit_format()
+ # Set seed
+ set_seed(args)
+
+ # Load pretrained model and tokenizer
+ if args.local_rank not in [-1, 0]:
+ # Make sure only the first process in distributed training will download model & vocab
+ torch.distributed.barrier()
+
+ args.model_type = args.model_type.lower()
+ config_class, model_class, tokenizer_class = MODEL_CLASSES[args.model_type]
+ config = config_class.from_pretrained(
+ args.config_name if args.config_name else args.model_name_or_path,
+ cache_dir=args.cache_dir if args.cache_dir else None,
+ )
+ tokenizer = tokenizer_class.from_pretrained(
+ args.tokenizer_name if args.tokenizer_name else args.model_name_or_path,
+ do_lower_case=args.do_lower_case,
+ cache_dir=args.cache_dir if args.cache_dir else None,
+ )
+ model = model_class.from_pretrained(
+ args.model_name_or_path,
+ from_tf=bool(".ckpt" in args.model_name_or_path),
+ config=config,
+ cache_dir=args.cache_dir if args.cache_dir else None,
+ )
+
+ if args.teacher_type is not None:
+ assert args.teacher_name_or_path is not None
+ assert args.alpha_ce > 0.0
+ assert args.alpha_ce + args.alpha_squad > 0.0
+ assert args.teacher_type != "distilbert", "We constraint teachers not to be of type DistilBERT."
+ teacher_config_class, teacher_model_class, _ = MODEL_CLASSES[args.teacher_type]
+ teacher_config = teacher_config_class.from_pretrained(
+ args.teacher_name_or_path, cache_dir=args.cache_dir if args.cache_dir else None
+ )
+ teacher = teacher_model_class.from_pretrained(
+ args.teacher_name_or_path, config=teacher_config, cache_dir=args.cache_dir if args.cache_dir else None
+ )
+ teacher.to(args.device)
+ else:
+ teacher = None
+
+ if args.local_rank == 0:
+ # Make sure only the first process in distributed training will download model & vocab
+ torch.distributed.barrier()
+
+ model.to(args.device)
+
+ logger.info("Training/evaluation parameters %s", args)
+
+ # Before we do anything with models, we want to ensure that we get fp16 execution of torch.einsum if args.fp16 is set.
+ # Otherwise it'll default to "promote" mode, and we'll get fp32 operations. Note that running `--fp16_opt_level="O2"` will
+ # remove the need for this code, but it is still valid.
+ if args.fp16:
+ try:
+ import apex
+
+ apex.amp.register_half_function(torch, "einsum")
+ except ImportError:
+ raise ImportError("Please install apex from https://www.github.com/nvidia/apex to use fp16 training.")
+
+ # Training
+ if args.do_train:
+ train_dataset = load_and_cache_examples(args, tokenizer, evaluate=False, output_examples=False)
+ global_step, tr_loss = train(args, train_dataset, model, tokenizer, teacher=teacher)
+ logger.info(" global_step = %s, average loss = %s", global_step, tr_loss)
+
+ # Save the trained model and the tokenizer
+ if args.do_train and (args.local_rank == -1 or torch.distributed.get_rank() == 0):
+ logger.info("Saving model checkpoint to %s", args.output_dir)
+ # Save a trained model, configuration and tokenizer using `save_pretrained()`.
+ # They can then be reloaded using `from_pretrained()`
+ model_to_save = (
+ model.module if hasattr(model, "module") else model
+ ) # Take care of distributed/parallel training
+ model_to_save.save_pretrained(args.output_dir)
+ tokenizer.save_pretrained(args.output_dir)
+
+ # Good practice: save your training arguments together with the trained model
+ torch.save(args, os.path.join(args.output_dir, "training_args.bin"))
+
+ # Load a trained model and vocabulary that you have fine-tuned
+ model = model_class.from_pretrained(args.output_dir)
+ tokenizer = tokenizer_class.from_pretrained(args.output_dir, do_lower_case=args.do_lower_case)
+ model.to(args.device)
+
+ # Evaluation - we can ask to evaluate all the checkpoints (sub-directories) in a directory
+ results = {}
+ if args.do_eval and args.local_rank in [-1, 0]:
+ if args.do_train:
+ logger.info("Loading checkpoints saved during training for evaluation")
+ checkpoints = [args.output_dir]
+ if args.eval_all_checkpoints:
+ checkpoints = [
+ os.path.dirname(c) for c in sorted(glob.glob(args.output_dir + "/**/" + WEIGHTS_NAME, recursive=True))
+ ]
+
+ logger.info("Evaluate the following checkpoints: %s", checkpoints)
+
+ for checkpoint in checkpoints:
+ # Reload the model
+ global_step = checkpoint.split("-")[-1] if len(checkpoints) > 1 else ""
+ model = model_class.from_pretrained(checkpoint)
+ model.to(args.device)
+
+ # Evaluate
+ result = evaluate(args, model, tokenizer, prefix=global_step)
+
+ result = {k + ("_{}".format(global_step) if global_step else ""): v for k, v in result.items()}
+ results.update(result)
+
+ logger.info("Results: {}".format(results))
+
+ return results
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/scripts/binarized_data.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/scripts/binarized_data.py
new file mode 100644
index 0000000000000000000000000000000000000000..3fc3214acf7ff9ea9543a04a86595f93d7b113ab
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/scripts/binarized_data.py
@@ -0,0 +1,97 @@
+# coding=utf-8
+# Copyright 2019-present, the HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Preprocessing script before distillation.
+"""
+
+import argparse
+import logging
+import pickle
+import random
+import time
+
+import numpy as np
+
+from transformers import BertTokenizer, GPT2Tokenizer, RobertaTokenizer
+
+
+logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s", datefmt="%m/%d/%Y %H:%M:%S", level=logging.INFO
+)
+logger = logging.getLogger(__name__)
+
+
+def main():
+ parser = argparse.ArgumentParser(
+ description="Preprocess the data to avoid re-doing it several times by (tokenization + token_to_ids)."
+ )
+ parser.add_argument("--file_path", type=str, default="data/dump.txt", help="The path to the data.")
+ parser.add_argument("--tokenizer_type", type=str, default="bert", choices=["bert", "roberta", "gpt2"])
+ parser.add_argument("--tokenizer_name", type=str, default="bert-base-uncased", help="The tokenizer to use.")
+ parser.add_argument("--dump_file", type=str, default="data/dump", help="The dump file prefix.")
+ args = parser.parse_args()
+
+ logger.info(f"Loading Tokenizer ({args.tokenizer_name})")
+ if args.tokenizer_type == "bert":
+ tokenizer = BertTokenizer.from_pretrained(args.tokenizer_name)
+ bos = tokenizer.special_tokens_map["cls_token"] # `[CLS]`
+ sep = tokenizer.special_tokens_map["sep_token"] # `[SEP]`
+ elif args.tokenizer_type == "roberta":
+ tokenizer = RobertaTokenizer.from_pretrained(args.tokenizer_name)
+ bos = tokenizer.special_tokens_map["cls_token"] # ``
+ sep = tokenizer.special_tokens_map["sep_token"] # ` `
+ elif args.tokenizer_type == "gpt2":
+ tokenizer = GPT2Tokenizer.from_pretrained(args.tokenizer_name)
+ bos = tokenizer.special_tokens_map["bos_token"] # `<|endoftext|>`
+ sep = tokenizer.special_tokens_map["eos_token"] # `<|endoftext|>`
+
+ logger.info(f"Loading text from {args.file_path}")
+ with open(args.file_path, "r", encoding="utf8") as fp:
+ data = fp.readlines()
+
+ logger.info("Start encoding")
+ logger.info(f"{len(data)} examples to process.")
+
+ rslt = []
+ iter = 0
+ interval = 10000
+ start = time.time()
+ for text in data:
+ text = f"{bos} {text.strip()} {sep}"
+ token_ids = tokenizer.encode(text, add_special_tokens=False)
+ rslt.append(token_ids)
+
+ iter += 1
+ if iter % interval == 0:
+ end = time.time()
+ logger.info(f"{iter} examples processed. - {(end-start):.2f}s/{interval}expl")
+ start = time.time()
+ logger.info("Finished binarization")
+ logger.info(f"{len(data)} examples processed.")
+
+ dp_file = f"{args.dump_file}.{args.tokenizer_name}.pickle"
+ vocab_size = tokenizer.vocab_size
+ if vocab_size < (1 << 16):
+ rslt_ = [np.uint16(d) for d in rslt]
+ else:
+ rslt_ = [np.int32(d) for d in rslt]
+ random.shuffle(rslt_)
+ logger.info(f"Dump to {dp_file}")
+ with open(dp_file, "wb") as handle:
+ pickle.dump(rslt_, handle, protocol=pickle.HIGHEST_PROTOCOL)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/scripts/extract.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/scripts/extract.py
new file mode 100644
index 0000000000000000000000000000000000000000..c45821d187312a3e5b644c3f2eab13183d5cbd0f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/scripts/extract.py
@@ -0,0 +1,106 @@
+# coding=utf-8
+# Copyright 2019-present, the HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Preprocessing script before training the distilled model.
+Specific to RoBERTa -> DistilRoBERTa and GPT2 -> DistilGPT2.
+"""
+
+import argparse
+
+import torch
+
+from transformers import GPT2LMHeadModel, RobertaForMaskedLM
+
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser(
+ description=(
+ "Extraction some layers of the full RobertaForMaskedLM or GPT2LMHeadModel for Transfer Learned"
+ " Distillation"
+ )
+ )
+ parser.add_argument("--model_type", default="roberta", choices=["roberta", "gpt2"])
+ parser.add_argument("--model_name", default="roberta-large", type=str)
+ parser.add_argument("--dump_checkpoint", default="serialization_dir/tf_roberta_048131723.pth", type=str)
+ parser.add_argument("--vocab_transform", action="store_true")
+ args = parser.parse_args()
+
+ if args.model_type == "roberta":
+ model = RobertaForMaskedLM.from_pretrained(args.model_name)
+ prefix = "roberta"
+ elif args.model_type == "gpt2":
+ model = GPT2LMHeadModel.from_pretrained(args.model_name)
+ prefix = "transformer"
+
+ state_dict = model.state_dict()
+ compressed_sd = {}
+
+ # Embeddings #
+ if args.model_type == "gpt2":
+ for param_name in ["wte.weight", "wpe.weight"]:
+ compressed_sd[f"{prefix}.{param_name}"] = state_dict[f"{prefix}.{param_name}"]
+ else:
+ for w in ["word_embeddings", "position_embeddings", "token_type_embeddings"]:
+ param_name = f"{prefix}.embeddings.{w}.weight"
+ compressed_sd[param_name] = state_dict[param_name]
+ for w in ["weight", "bias"]:
+ param_name = f"{prefix}.embeddings.LayerNorm.{w}"
+ compressed_sd[param_name] = state_dict[param_name]
+
+ # Transformer Blocks #
+ std_idx = 0
+ for teacher_idx in [0, 2, 4, 7, 9, 11]:
+ if args.model_type == "gpt2":
+ for layer in ["ln_1", "attn.c_attn", "attn.c_proj", "ln_2", "mlp.c_fc", "mlp.c_proj"]:
+ for w in ["weight", "bias"]:
+ compressed_sd[f"{prefix}.h.{std_idx}.{layer}.{w}"] = state_dict[
+ f"{prefix}.h.{teacher_idx}.{layer}.{w}"
+ ]
+ compressed_sd[f"{prefix}.h.{std_idx}.attn.bias"] = state_dict[f"{prefix}.h.{teacher_idx}.attn.bias"]
+ else:
+ for layer in [
+ "attention.self.query",
+ "attention.self.key",
+ "attention.self.value",
+ "attention.output.dense",
+ "attention.output.LayerNorm",
+ "intermediate.dense",
+ "output.dense",
+ "output.LayerNorm",
+ ]:
+ for w in ["weight", "bias"]:
+ compressed_sd[f"{prefix}.encoder.layer.{std_idx}.{layer}.{w}"] = state_dict[
+ f"{prefix}.encoder.layer.{teacher_idx}.{layer}.{w}"
+ ]
+ std_idx += 1
+
+ # Language Modeling Head ###s
+ if args.model_type == "roberta":
+ for layer in ["lm_head.decoder.weight", "lm_head.bias"]:
+ compressed_sd[f"{layer}"] = state_dict[f"{layer}"]
+ if args.vocab_transform:
+ for w in ["weight", "bias"]:
+ compressed_sd[f"lm_head.dense.{w}"] = state_dict[f"lm_head.dense.{w}"]
+ compressed_sd[f"lm_head.layer_norm.{w}"] = state_dict[f"lm_head.layer_norm.{w}"]
+ elif args.model_type == "gpt2":
+ for w in ["weight", "bias"]:
+ compressed_sd[f"{prefix}.ln_f.{w}"] = state_dict[f"{prefix}.ln_f.{w}"]
+ compressed_sd["lm_head.weight"] = state_dict["lm_head.weight"]
+
+ print(f"N layers selected for distillation: {std_idx}")
+ print(f"Number of params transferred for distillation: {len(compressed_sd.keys())}")
+
+ print(f"Save transferred checkpoint to {args.dump_checkpoint}.")
+ torch.save(compressed_sd, args.dump_checkpoint)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/scripts/extract_distilbert.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/scripts/extract_distilbert.py
new file mode 100644
index 0000000000000000000000000000000000000000..8637970c5117c5e9072ff4b18bc7d36acdd6c398
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/scripts/extract_distilbert.py
@@ -0,0 +1,96 @@
+# coding=utf-8
+# Copyright 2019-present, the HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Preprocessing script before training DistilBERT.
+Specific to BERT -> DistilBERT.
+"""
+
+import argparse
+
+import torch
+
+from transformers import BertForMaskedLM
+
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser(
+ description=(
+ "Extraction some layers of the full BertForMaskedLM or RObertaForMaskedLM for Transfer Learned"
+ " Distillation"
+ )
+ )
+ parser.add_argument("--model_type", default="bert", choices=["bert"])
+ parser.add_argument("--model_name", default="bert-base-uncased", type=str)
+ parser.add_argument("--dump_checkpoint", default="serialization_dir/tf_bert-base-uncased_0247911.pth", type=str)
+ parser.add_argument("--vocab_transform", action="store_true")
+ args = parser.parse_args()
+
+ if args.model_type == "bert":
+ model = BertForMaskedLM.from_pretrained(args.model_name)
+ prefix = "bert"
+ else:
+ raise ValueError('args.model_type should be "bert".')
+
+ state_dict = model.state_dict()
+ compressed_sd = {}
+
+ for w in ["word_embeddings", "position_embeddings"]:
+ compressed_sd[f"distilbert.embeddings.{w}.weight"] = state_dict[f"{prefix}.embeddings.{w}.weight"]
+ for w in ["weight", "bias"]:
+ compressed_sd[f"distilbert.embeddings.LayerNorm.{w}"] = state_dict[f"{prefix}.embeddings.LayerNorm.{w}"]
+
+ std_idx = 0
+ for teacher_idx in [0, 2, 4, 7, 9, 11]:
+ for w in ["weight", "bias"]:
+ compressed_sd[f"distilbert.transformer.layer.{std_idx}.attention.q_lin.{w}"] = state_dict[
+ f"{prefix}.encoder.layer.{teacher_idx}.attention.self.query.{w}"
+ ]
+ compressed_sd[f"distilbert.transformer.layer.{std_idx}.attention.k_lin.{w}"] = state_dict[
+ f"{prefix}.encoder.layer.{teacher_idx}.attention.self.key.{w}"
+ ]
+ compressed_sd[f"distilbert.transformer.layer.{std_idx}.attention.v_lin.{w}"] = state_dict[
+ f"{prefix}.encoder.layer.{teacher_idx}.attention.self.value.{w}"
+ ]
+
+ compressed_sd[f"distilbert.transformer.layer.{std_idx}.attention.out_lin.{w}"] = state_dict[
+ f"{prefix}.encoder.layer.{teacher_idx}.attention.output.dense.{w}"
+ ]
+ compressed_sd[f"distilbert.transformer.layer.{std_idx}.sa_layer_norm.{w}"] = state_dict[
+ f"{prefix}.encoder.layer.{teacher_idx}.attention.output.LayerNorm.{w}"
+ ]
+
+ compressed_sd[f"distilbert.transformer.layer.{std_idx}.ffn.lin1.{w}"] = state_dict[
+ f"{prefix}.encoder.layer.{teacher_idx}.intermediate.dense.{w}"
+ ]
+ compressed_sd[f"distilbert.transformer.layer.{std_idx}.ffn.lin2.{w}"] = state_dict[
+ f"{prefix}.encoder.layer.{teacher_idx}.output.dense.{w}"
+ ]
+ compressed_sd[f"distilbert.transformer.layer.{std_idx}.output_layer_norm.{w}"] = state_dict[
+ f"{prefix}.encoder.layer.{teacher_idx}.output.LayerNorm.{w}"
+ ]
+ std_idx += 1
+
+ compressed_sd["vocab_projector.weight"] = state_dict["cls.predictions.decoder.weight"]
+ compressed_sd["vocab_projector.bias"] = state_dict["cls.predictions.bias"]
+ if args.vocab_transform:
+ for w in ["weight", "bias"]:
+ compressed_sd[f"vocab_transform.{w}"] = state_dict[f"cls.predictions.transform.dense.{w}"]
+ compressed_sd[f"vocab_layer_norm.{w}"] = state_dict[f"cls.predictions.transform.LayerNorm.{w}"]
+
+ print(f"N layers selected for distillation: {std_idx}")
+ print(f"Number of params transferred for distillation: {len(compressed_sd.keys())}")
+
+ print(f"Save transferred checkpoint to {args.dump_checkpoint}.")
+ torch.save(compressed_sd, args.dump_checkpoint)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/scripts/token_counts.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/scripts/token_counts.py
new file mode 100644
index 0000000000000000000000000000000000000000..2f80bf31f47778b280944f4307e633d32e7923ce
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/scripts/token_counts.py
@@ -0,0 +1,57 @@
+# coding=utf-8
+# Copyright 2019-present, the HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Preprocessing script before training the distilled model.
+"""
+
+import argparse
+import logging
+import pickle
+from collections import Counter
+
+
+logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s", datefmt="%m/%d/%Y %H:%M:%S", level=logging.INFO
+)
+logger = logging.getLogger(__name__)
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser(
+ description="Token Counts for smoothing the masking probabilities in MLM (cf XLM/word2vec)"
+ )
+ parser.add_argument(
+ "--data_file", type=str, default="data/dump.bert-base-uncased.pickle", help="The binarized dataset."
+ )
+ parser.add_argument(
+ "--token_counts_dump", type=str, default="data/token_counts.bert-base-uncased.pickle", help="The dump file."
+ )
+ parser.add_argument("--vocab_size", default=30522, type=int)
+ args = parser.parse_args()
+
+ logger.info(f"Loading data from {args.data_file}")
+ with open(args.data_file, "rb") as fp:
+ data = pickle.load(fp)
+
+ logger.info("Counting occurrences for MLM.")
+ counter = Counter()
+ for tk_ids in data:
+ counter.update(tk_ids)
+ counts = [0] * args.vocab_size
+ for k, v in counter.items():
+ counts[k] = v
+
+ logger.info(f"Dump to {args.token_counts_dump}")
+ with open(args.token_counts_dump, "wb") as handle:
+ pickle.dump(counts, handle, protocol=pickle.HIGHEST_PROTOCOL)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/train.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/train.py
new file mode 100644
index 0000000000000000000000000000000000000000..15d98ace09b56c7aa0e4ea85a18524d4c10f4b5f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/train.py
@@ -0,0 +1,325 @@
+# coding=utf-8
+# Copyright 2019-present, the HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Training the distilled model.
+Supported architectures include: BERT -> DistilBERT, RoBERTa -> DistilRoBERTa, GPT2 -> DistilGPT2.
+"""
+
+import argparse
+import json
+import os
+import pickle
+import shutil
+
+import numpy as np
+import torch
+from distiller import Distiller
+from lm_seqs_dataset import LmSeqsDataset
+
+from transformers import (
+ BertConfig,
+ BertForMaskedLM,
+ BertTokenizer,
+ DistilBertConfig,
+ DistilBertForMaskedLM,
+ DistilBertTokenizer,
+ GPT2Config,
+ GPT2LMHeadModel,
+ GPT2Tokenizer,
+ RobertaConfig,
+ RobertaForMaskedLM,
+ RobertaTokenizer,
+)
+from utils import git_log, init_gpu_params, logger, set_seed
+
+
+MODEL_CLASSES = {
+ "distilbert": (DistilBertConfig, DistilBertForMaskedLM, DistilBertTokenizer),
+ "roberta": (RobertaConfig, RobertaForMaskedLM, RobertaTokenizer),
+ "bert": (BertConfig, BertForMaskedLM, BertTokenizer),
+ "gpt2": (GPT2Config, GPT2LMHeadModel, GPT2Tokenizer),
+}
+
+
+def sanity_checks(args):
+ """
+ A bunch of args sanity checks to perform even starting...
+ """
+ assert (args.mlm and args.alpha_mlm > 0.0) or (not args.mlm and args.alpha_mlm == 0.0)
+ assert (args.alpha_mlm > 0.0 and args.alpha_clm == 0.0) or (args.alpha_mlm == 0.0 and args.alpha_clm > 0.0)
+ if args.mlm:
+ assert os.path.isfile(args.token_counts)
+ assert (args.student_type in ["roberta", "distilbert"]) and (args.teacher_type in ["roberta", "bert"])
+ else:
+ assert (args.student_type in ["gpt2"]) and (args.teacher_type in ["gpt2"])
+
+ assert args.teacher_type == args.student_type or (
+ args.student_type == "distilbert" and args.teacher_type == "bert"
+ )
+ assert os.path.isfile(args.student_config)
+ if args.student_pretrained_weights is not None:
+ assert os.path.isfile(args.student_pretrained_weights)
+
+ if args.freeze_token_type_embds:
+ assert args.student_type in ["roberta"]
+
+ assert args.alpha_ce >= 0.0
+ assert args.alpha_mlm >= 0.0
+ assert args.alpha_clm >= 0.0
+ assert args.alpha_mse >= 0.0
+ assert args.alpha_cos >= 0.0
+ assert args.alpha_ce + args.alpha_mlm + args.alpha_clm + args.alpha_mse + args.alpha_cos > 0.0
+
+
+def freeze_pos_embeddings(student, args):
+ if args.student_type == "roberta":
+ student.roberta.embeddings.position_embeddings.weight.requires_grad = False
+ elif args.student_type == "gpt2":
+ student.transformer.wpe.weight.requires_grad = False
+
+
+def freeze_token_type_embeddings(student, args):
+ if args.student_type == "roberta":
+ student.roberta.embeddings.token_type_embeddings.weight.requires_grad = False
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Training")
+ parser.add_argument("--force", action="store_true", help="Overwrite dump_path if it already exists.")
+
+ parser.add_argument(
+ "--dump_path", type=str, required=True, help="The output directory (log, checkpoints, parameters, etc.)"
+ )
+ parser.add_argument(
+ "--data_file",
+ type=str,
+ required=True,
+ help="The binarized file (tokenized + tokens_to_ids) and grouped by sequence.",
+ )
+
+ parser.add_argument(
+ "--student_type",
+ type=str,
+ choices=["distilbert", "roberta", "gpt2"],
+ required=True,
+ help="The student type (DistilBERT, RoBERTa).",
+ )
+ parser.add_argument("--student_config", type=str, required=True, help="Path to the student configuration.")
+ parser.add_argument(
+ "--student_pretrained_weights", default=None, type=str, help="Load student initialization checkpoint."
+ )
+
+ parser.add_argument(
+ "--teacher_type", choices=["bert", "roberta", "gpt2"], required=True, help="Teacher type (BERT, RoBERTa)."
+ )
+ parser.add_argument("--teacher_name", type=str, required=True, help="The teacher model.")
+
+ parser.add_argument("--temperature", default=2.0, type=float, help="Temperature for the softmax temperature.")
+ parser.add_argument(
+ "--alpha_ce", default=0.5, type=float, help="Linear weight for the distillation loss. Must be >=0."
+ )
+ parser.add_argument(
+ "--alpha_mlm",
+ default=0.0,
+ type=float,
+ help="Linear weight for the MLM loss. Must be >=0. Should be used in conjunction with `mlm` flag.",
+ )
+ parser.add_argument("--alpha_clm", default=0.5, type=float, help="Linear weight for the CLM loss. Must be >=0.")
+ parser.add_argument("--alpha_mse", default=0.0, type=float, help="Linear weight of the MSE loss. Must be >=0.")
+ parser.add_argument(
+ "--alpha_cos", default=0.0, type=float, help="Linear weight of the cosine embedding loss. Must be >=0."
+ )
+
+ parser.add_argument(
+ "--mlm", action="store_true", help="The LM step: MLM or CLM. If `mlm` is True, the MLM is used over CLM."
+ )
+ parser.add_argument(
+ "--mlm_mask_prop",
+ default=0.15,
+ type=float,
+ help="Proportion of tokens for which we need to make a prediction.",
+ )
+ parser.add_argument("--word_mask", default=0.8, type=float, help="Proportion of tokens to mask out.")
+ parser.add_argument("--word_keep", default=0.1, type=float, help="Proportion of tokens to keep.")
+ parser.add_argument("--word_rand", default=0.1, type=float, help="Proportion of tokens to randomly replace.")
+ parser.add_argument(
+ "--mlm_smoothing",
+ default=0.7,
+ type=float,
+ help="Smoothing parameter to emphasize more rare tokens (see XLM, similar to word2vec).",
+ )
+ parser.add_argument("--token_counts", type=str, help="The token counts in the data_file for MLM.")
+
+ parser.add_argument(
+ "--restrict_ce_to_mask",
+ action="store_true",
+ help="If true, compute the distillation loss only the [MLM] prediction distribution.",
+ )
+ parser.add_argument(
+ "--freeze_pos_embs",
+ action="store_true",
+ help="Freeze positional embeddings during distillation. For student_type in ['roberta', 'gpt2'] only.",
+ )
+ parser.add_argument(
+ "--freeze_token_type_embds",
+ action="store_true",
+ help="Freeze token type embeddings during distillation if existent. For student_type in ['roberta'] only.",
+ )
+
+ parser.add_argument("--n_epoch", type=int, default=3, help="Number of pass on the whole dataset.")
+ parser.add_argument("--batch_size", type=int, default=5, help="Batch size (for each process).")
+ parser.add_argument(
+ "--group_by_size",
+ action="store_false",
+ help="If true, group sequences that have similar length into the same batch. Default is true.",
+ )
+
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=50,
+ help="Gradient accumulation for larger training batches.",
+ )
+ parser.add_argument("--warmup_prop", default=0.05, type=float, help="Linear warmup proportion.")
+ parser.add_argument("--weight_decay", default=0.0, type=float, help="Weight decay if we apply some.")
+ parser.add_argument("--learning_rate", default=5e-4, type=float, help="The initial learning rate for Adam.")
+ parser.add_argument("--adam_epsilon", default=1e-6, type=float, help="Epsilon for Adam optimizer.")
+ parser.add_argument("--max_grad_norm", default=5.0, type=float, help="Max gradient norm.")
+ parser.add_argument("--initializer_range", default=0.02, type=float, help="Random initialization range.")
+
+ parser.add_argument(
+ "--fp16",
+ action="store_true",
+ help="Whether to use 16-bit (mixed) precision (through NVIDIA apex) instead of 32-bit",
+ )
+ parser.add_argument(
+ "--fp16_opt_level",
+ type=str,
+ default="O1",
+ help=(
+ "For fp16: Apex AMP optimization level selected in ['O0', 'O1', 'O2', and 'O3']. "
+ "See details at https://nvidia.github.io/apex/amp.html"
+ ),
+ )
+ parser.add_argument("--n_gpu", type=int, default=1, help="Number of GPUs in the node.")
+ parser.add_argument("--local_rank", type=int, default=-1, help="Distributed training - Local rank")
+ parser.add_argument("--seed", type=int, default=56, help="Random seed")
+
+ parser.add_argument("--log_interval", type=int, default=500, help="Tensorboard logging interval.")
+ parser.add_argument("--checkpoint_interval", type=int, default=4000, help="Checkpoint interval.")
+ args = parser.parse_args()
+ sanity_checks(args)
+
+ # ARGS #
+ init_gpu_params(args)
+ set_seed(args)
+ if args.is_master:
+ if os.path.exists(args.dump_path):
+ if not args.force:
+ raise ValueError(
+ f"Serialization dir {args.dump_path} already exists, but you have not precised wheter to overwrite"
+ " itUse `--force` if you want to overwrite it"
+ )
+ else:
+ shutil.rmtree(args.dump_path)
+
+ if not os.path.exists(args.dump_path):
+ os.makedirs(args.dump_path)
+ logger.info(f"Experiment will be dumped and logged in {args.dump_path}")
+
+ # SAVE PARAMS #
+ logger.info(f"Param: {args}")
+ with open(os.path.join(args.dump_path, "parameters.json"), "w") as f:
+ json.dump(vars(args), f, indent=4)
+ git_log(args.dump_path)
+
+ student_config_class, student_model_class, _ = MODEL_CLASSES[args.student_type]
+ teacher_config_class, teacher_model_class, teacher_tokenizer_class = MODEL_CLASSES[args.teacher_type]
+
+ # TOKENIZER #
+ tokenizer = teacher_tokenizer_class.from_pretrained(args.teacher_name)
+ special_tok_ids = {}
+ for tok_name, tok_symbol in tokenizer.special_tokens_map.items():
+ idx = tokenizer.all_special_tokens.index(tok_symbol)
+ special_tok_ids[tok_name] = tokenizer.all_special_ids[idx]
+ logger.info(f"Special tokens {special_tok_ids}")
+ args.special_tok_ids = special_tok_ids
+ args.max_model_input_size = tokenizer.max_model_input_sizes[args.teacher_name]
+
+ # DATA LOADER #
+ logger.info(f"Loading data from {args.data_file}")
+ with open(args.data_file, "rb") as fp:
+ data = pickle.load(fp)
+
+ if args.mlm:
+ logger.info(f"Loading token counts from {args.token_counts} (already pre-computed)")
+ with open(args.token_counts, "rb") as fp:
+ counts = pickle.load(fp)
+
+ token_probs = np.maximum(counts, 1) ** -args.mlm_smoothing
+ for idx in special_tok_ids.values():
+ token_probs[idx] = 0.0 # do not predict special tokens
+ token_probs = torch.from_numpy(token_probs)
+ else:
+ token_probs = None
+
+ train_lm_seq_dataset = LmSeqsDataset(params=args, data=data)
+ logger.info("Data loader created.")
+
+ # STUDENT #
+ logger.info(f"Loading student config from {args.student_config}")
+ stu_architecture_config = student_config_class.from_pretrained(args.student_config)
+ stu_architecture_config.output_hidden_states = True
+
+ if args.student_pretrained_weights is not None:
+ logger.info(f"Loading pretrained weights from {args.student_pretrained_weights}")
+ student = student_model_class.from_pretrained(args.student_pretrained_weights, config=stu_architecture_config)
+ else:
+ student = student_model_class(stu_architecture_config)
+
+ if args.n_gpu > 0:
+ student.to(f"cuda:{args.local_rank}")
+ logger.info("Student loaded.")
+
+ # TEACHER #
+ teacher = teacher_model_class.from_pretrained(args.teacher_name, output_hidden_states=True)
+ if args.n_gpu > 0:
+ teacher.to(f"cuda:{args.local_rank}")
+ logger.info(f"Teacher loaded from {args.teacher_name}.")
+
+ # FREEZING #
+ if args.freeze_pos_embs:
+ freeze_pos_embeddings(student, args)
+ if args.freeze_token_type_embds:
+ freeze_token_type_embeddings(student, args)
+
+ # SANITY CHECKS #
+ assert student.config.vocab_size == teacher.config.vocab_size
+ assert student.config.hidden_size == teacher.config.hidden_size
+ assert student.config.max_position_embeddings == teacher.config.max_position_embeddings
+ if args.mlm:
+ assert token_probs.size(0) == stu_architecture_config.vocab_size
+
+ # DISTILLER #
+ torch.cuda.empty_cache()
+ distiller = Distiller(
+ params=args, dataset=train_lm_seq_dataset, token_probs=token_probs, student=student, teacher=teacher
+ )
+ distiller.train()
+ logger.info("Let's go get some drinks.")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/training_configs/distilbert-base-cased.json b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/training_configs/distilbert-base-cased.json
new file mode 100644
index 0000000000000000000000000000000000000000..d4f524d704c3fa7135f77e54a333e62c3b4ce227
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/training_configs/distilbert-base-cased.json
@@ -0,0 +1,15 @@
+{
+ "activation": "gelu",
+ "attention_dropout": 0.1,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "n_heads": 12,
+ "n_layers": 6,
+ "sinusoidal_pos_embds": true,
+ "tie_weights_": true,
+ "vocab_size": 28996
+ }
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/training_configs/distilbert-base-multilingual-cased.json b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/training_configs/distilbert-base-multilingual-cased.json
new file mode 100644
index 0000000000000000000000000000000000000000..f76e7febcba536f7ee6137e70ffca0acae649bea
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/training_configs/distilbert-base-multilingual-cased.json
@@ -0,0 +1,15 @@
+{
+ "activation": "gelu",
+ "attention_dropout": 0.1,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "n_heads": 12,
+ "n_layers": 6,
+ "sinusoidal_pos_embds": true,
+ "tie_weights_": true,
+ "vocab_size": 119547
+ }
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/training_configs/distilbert-base-uncased.json b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/training_configs/distilbert-base-uncased.json
new file mode 100644
index 0000000000000000000000000000000000000000..15d1e7fe00e63100b602a0d7db0cdbf16f7e6ff0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/training_configs/distilbert-base-uncased.json
@@ -0,0 +1,15 @@
+{
+ "activation": "gelu",
+ "attention_dropout": 0.1,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "n_heads": 12,
+ "n_layers": 6,
+ "sinusoidal_pos_embds": true,
+ "tie_weights_": true,
+ "vocab_size": 30522
+ }
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/training_configs/distilgpt2.json b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/training_configs/distilgpt2.json
new file mode 100644
index 0000000000000000000000000000000000000000..9820ac93b8c72d9c1629a6470f4f3efa5e58f56b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/training_configs/distilgpt2.json
@@ -0,0 +1,9 @@
+{
+ "initializer_range": 0.02,
+ "layer_norm_epsilon": 0.00001,
+ "n_embd": 768,
+ "n_head": 12,
+ "n_layer": 6,
+ "n_positions": 1024,
+ "vocab_size": 50257
+}
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/training_configs/distilroberta-base.json b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/training_configs/distilroberta-base.json
new file mode 100644
index 0000000000000000000000000000000000000000..2d90ef6380a0e4d54dbab8b1a151f7162665c0da
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/training_configs/distilroberta-base.json
@@ -0,0 +1,14 @@
+{
+ "vocab_size": 50265,
+ "hidden_size": 768,
+ "num_hidden_layers": 6,
+ "num_attention_heads": 12,
+ "intermediate_size": 3072,
+ "hidden_act": "gelu",
+ "hidden_dropout_prob": 0.1,
+ "attention_probs_dropout_prob": 0.1,
+ "max_position_embeddings": 514,
+ "type_vocab_size": 1,
+ "initializer_range": 0.02,
+ "layer_norm_eps": 0.00001
+}
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/utils.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..e86d2593bbd9918c1a1ae1822807235ca4b5519c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/distillation/utils.py
@@ -0,0 +1,134 @@
+# coding=utf-8
+# Copyright 2019-present, the HuggingFace Inc. team and Facebook, Inc.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Utils to train DistilBERT
+adapted in part from Facebook, Inc XLM model (https://github.com/facebookresearch/XLM)
+"""
+
+import json
+import logging
+import os
+import socket
+
+import git
+import numpy as np
+import torch
+
+
+logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - PID: %(process)d - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+)
+logger = logging.getLogger(__name__)
+
+
+def git_log(folder_path: str):
+ """
+ Log commit info.
+ """
+ repo = git.Repo(search_parent_directories=True)
+ repo_infos = {
+ "repo_id": str(repo),
+ "repo_sha": str(repo.head.object.hexsha),
+ "repo_branch": str(repo.active_branch),
+ }
+
+ with open(os.path.join(folder_path, "git_log.json"), "w") as f:
+ json.dump(repo_infos, f, indent=4)
+
+
+def init_gpu_params(params):
+ """
+ Handle single and multi-GPU / multi-node.
+ """
+ if params.n_gpu <= 0:
+ params.local_rank = 0
+ params.master_port = -1
+ params.is_master = True
+ params.multi_gpu = False
+ return
+
+ assert torch.cuda.is_available()
+
+ logger.info("Initializing GPUs")
+ if params.n_gpu > 1:
+ assert params.local_rank != -1
+
+ params.world_size = int(os.environ["WORLD_SIZE"])
+ params.n_gpu_per_node = int(os.environ["N_GPU_NODE"])
+ params.global_rank = int(os.environ["RANK"])
+
+ # number of nodes / node ID
+ params.n_nodes = params.world_size // params.n_gpu_per_node
+ params.node_id = params.global_rank // params.n_gpu_per_node
+ params.multi_gpu = True
+
+ assert params.n_nodes == int(os.environ["N_NODES"])
+ assert params.node_id == int(os.environ["NODE_RANK"])
+
+ # local job (single GPU)
+ else:
+ assert params.local_rank == -1
+
+ params.n_nodes = 1
+ params.node_id = 0
+ params.local_rank = 0
+ params.global_rank = 0
+ params.world_size = 1
+ params.n_gpu_per_node = 1
+ params.multi_gpu = False
+
+ # sanity checks
+ assert params.n_nodes >= 1
+ assert 0 <= params.node_id < params.n_nodes
+ assert 0 <= params.local_rank <= params.global_rank < params.world_size
+ assert params.world_size == params.n_nodes * params.n_gpu_per_node
+
+ # define whether this is the master process / if we are in multi-node distributed mode
+ params.is_master = params.node_id == 0 and params.local_rank == 0
+ params.multi_node = params.n_nodes > 1
+
+ # summary
+ PREFIX = f"--- Global rank: {params.global_rank} - "
+ logger.info(PREFIX + "Number of nodes: %i" % params.n_nodes)
+ logger.info(PREFIX + "Node ID : %i" % params.node_id)
+ logger.info(PREFIX + "Local rank : %i" % params.local_rank)
+ logger.info(PREFIX + "World size : %i" % params.world_size)
+ logger.info(PREFIX + "GPUs per node : %i" % params.n_gpu_per_node)
+ logger.info(PREFIX + "Master : %s" % str(params.is_master))
+ logger.info(PREFIX + "Multi-node : %s" % str(params.multi_node))
+ logger.info(PREFIX + "Multi-GPU : %s" % str(params.multi_gpu))
+ logger.info(PREFIX + "Hostname : %s" % socket.gethostname())
+
+ # set GPU device
+ torch.cuda.set_device(params.local_rank)
+
+ # initialize multi-GPU
+ if params.multi_gpu:
+ logger.info("Initializing PyTorch distributed")
+ torch.distributed.init_process_group(
+ init_method="env://",
+ backend="nccl",
+ )
+
+
+def set_seed(args):
+ """
+ Set the random seed.
+ """
+ np.random.seed(args.seed)
+ torch.manual_seed(args.seed)
+ if args.n_gpu > 0:
+ torch.cuda.manual_seed_all(args.seed)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..5ebcee07fcb684b27c57bea865d89006536a9682
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/README.md
@@ -0,0 +1,88 @@
+
+
+
+ Implemented by sayef .
+
+
+## Overview
+
+The FSNER model was proposed in [Example-Based Named Entity Recognition](https://arxiv.org/abs/2008.10570) by Morteza Ziyadi, Yuting Sun, Abhishek Goswami, Jade Huang, Weizhu Chen. To identify entity spans in a new domain, it uses a train-free few-shot learning approach inspired by question-answering.
+
+
+
+## Abstract
+----
+> We present a novel approach to named entity recognition (NER) in the presence of scarce data that we call example-based NER. Our train-free few-shot learning approach takes inspiration from question-answering to identify entity spans in a new and unseen domain. In comparison with the current state-of-the-art, the proposed method performs significantly better, especially when using a low number of support examples.
+
+
+
+## Model Training Details
+-----
+
+| identifier | epochs | datasets |
+| ---------- |:----------:| :-----:|
+| [sayef/fsner-bert-base-uncased](https://huggingface.co/sayef/fsner-bert-base-uncased) | 10 | ontonotes5, conll2003, wnut2017, and fin (Alvarado et al.). |
+
+
+## Installation and Example Usage
+------
+
+You can use the FSNER model in 3 ways:
+
+1. Install directly from PyPI: `pip install fsner` and import the model as shown in the code example below
+
+ or
+
+2. Install from source: `python setup.py install` and import the model as shown in the code example below
+
+ or
+
+3. Clone repo and change directory to `src` and import the model as shown in the code example below
+
+
+
+```python
+from fsner import FSNERModel, FSNERTokenizerUtils
+
+model = FSNERModel("sayef/fsner-bert-base-uncased")
+
+tokenizer = FSNERTokenizerUtils("sayef/fsner-bert-base-uncased")
+
+# size of query and supports must be the same. If you want to find all the entitites in one particular query, just repeat the same query n times where n is equal to the number of supports (or entities).
+
+
+query = [
+ 'KWE 4000 can reach with a maximum speed from up to 450 P/min an accuracy from 50 mg',
+ 'I would like to order a computer from eBay.',
+]
+
+# each list in supports are the examples of one entity type
+# wrap entities around with [E] and [/E] in the examples
+
+supports = [
+ [
+ 'Horizontal flow wrapper [E] Pack 403 [/E] features the new retrofit-kit „paper-ON-form“',
+ '[E] Paloma Pick-and-Place-Roboter [/E] arranges the bakery products for the downstream tray-forming equipment',
+ 'Finally, the new [E] Kliklok ACE [/E] carton former forms cartons and trays without the use of glue',
+ 'We set up our pilot plant with the right [E] FibreForm® [/E] configuration to make prototypes for your marketing tests and package validation',
+ 'The [E] CAR-T5 [/E] is a reliable, purely mechanically driven cartoning machine for versatile application fields'
+ ],
+ [
+ "[E] Walmart [/E] is a leading e-commerce company",
+ "I recently ordered a book from [E] Amazon [/E]",
+ "I ordered this from [E] ShopClues [/E]",
+ "[E] Flipkart [/E] started it's journey from zero"
+ ]
+ ]
+
+device = 'cpu'
+
+W_query = tokenizer.tokenize(query).to(device)
+W_supports = tokenizer.tokenize(supports).to(device)
+
+start_prob, end_prob = model(W_query, W_supports)
+
+output = tokenizer.extract_entity_from_scores(query, W_query, start_prob, end_prob, thresh=0.50)
+
+print(output)
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/pyproject.toml b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/pyproject.toml
new file mode 100644
index 0000000000000000000000000000000000000000..f00ba2f7a92b99c3cf2c67ec9d480ef312d47ff8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/pyproject.toml
@@ -0,0 +1,7 @@
+[build-system]
+requires = [
+ "setuptools>=57.4.0",
+ "wheel>=0.37.0",
+ "transformers>=4.9.2"
+]
+build-backend = "setuptools.build_meta"
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..f77cb020b2c1faf87572e2f705b36ebcaf2ed82e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/requirements.txt
@@ -0,0 +1 @@
+transformers>=4.9.2
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/setup.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/setup.py
new file mode 100644
index 0000000000000000000000000000000000000000..8ce34d0f7d9053b36d3cde98d251dfbc0ffe5a25
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/setup.py
@@ -0,0 +1,27 @@
+import setuptools
+
+
+with open("README.md", "r", encoding="utf-8") as fh:
+ long_description = fh.read()
+
+setuptools.setup(
+ name="fsner",
+ version="0.0.1",
+ author="msi sayef",
+ author_email="msi.sayef@gmail.com",
+ description="Few-shot Named Entity Recognition",
+ long_description=long_description,
+ long_description_content_type="text/markdown",
+ url="https://github.com/huggingface/transformers/tree/main/examples/research_projects/fsner",
+ project_urls={
+ "Bug Tracker": "https://github.com/huggingface/transformers/issues",
+ },
+ classifiers=[
+ "Programming Language :: Python :: 3",
+ "Operating System :: OS Independent",
+ ],
+ package_dir={"": "src"},
+ packages=setuptools.find_packages(where="src"),
+ python_requires=">=3.6",
+ install_requires=["torch>=1.9.0", "transformers>=4.9.2"],
+)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/src/fsner/__init__.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/src/fsner/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..130813cc119c1689912b3de28abb59cb18a92045
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/src/fsner/__init__.py
@@ -0,0 +1,5 @@
+from .model import FSNERModel
+from .tokenizer_utils import FSNERTokenizerUtils
+
+
+__all__ = ["FSNERModel", "FSNERTokenizerUtils"]
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/src/fsner/model.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/src/fsner/model.py
new file mode 100644
index 0000000000000000000000000000000000000000..0410340c4a9467113152a7486c4856a0e5b04ba3
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/src/fsner/model.py
@@ -0,0 +1,80 @@
+import torch
+
+from transformers import AutoModel
+
+
+class FSNERModel(torch.nn.Module):
+ """
+ The FSNER model implements a few-shot named entity recognition method from the paper `Example-Based Named Entity Recognition `__ by
+ Morteza Ziyadi, Yuting Sun, Abhishek Goswami, Jade Huang, Weizhu Chen. To identify entity spans in a new domain, it
+ uses a train-free few-shot learning approach inspired by question-answering.
+ """
+
+ def __init__(self, pretrained_model_name_or_path="sayef/fsner-bert-base-uncased"):
+ super(FSNERModel, self).__init__()
+
+ self.bert = AutoModel.from_pretrained(pretrained_model_name_or_path, return_dict=True)
+ self.cos = torch.nn.CosineSimilarity(3, 1e-08)
+ self.softmax = torch.nn.Softmax(dim=1)
+
+ def BERT(self, **inputs):
+ return self.bert(**inputs).last_hidden_state
+
+ def VectorSum(self, token_embeddings):
+ return token_embeddings.sum(2, keepdim=True)
+
+ def Atten(self, q_rep, S_rep, T=1):
+ return self.softmax(T * self.cos(q_rep, S_rep))
+
+ def forward(self, W_query, W_supports):
+ """
+ Find scores of each token being start and end token for an entity.
+ Args:
+ W_query (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of query sequence tokens in the vocabulary.
+ W_supports (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of support sequence tokens in the vocabulary.
+ Returns:
+ p_start (`torch.FloatTensor` of shape `(batch_size, sequence_length)`): Scores of each token as
+ being start token of an entity
+ p_end (`torch.FloatTensor` of shape `(batch_size, sequence_length)`): Scores of each token as
+ being end token of an entity
+ """
+
+ support_sizes = W_supports["sizes"].tolist()
+ start_token_id = W_supports["start_token_id"].item()
+ end_token_id = W_supports["end_token_id"].item()
+
+ del W_supports["sizes"]
+ del W_supports["start_token_id"]
+ del W_supports["end_token_id"]
+
+ q = self.BERT(**W_query)
+ S = self.BERT(**W_supports)
+
+ p_starts = None
+ p_ends = None
+
+ start_token_masks = W_supports["input_ids"] == start_token_id
+ end_token_masks = W_supports["input_ids"] == end_token_id
+
+ for i, size in enumerate(support_sizes):
+ if i == 0:
+ s = 0
+ else:
+ s = support_sizes[i - 1]
+
+ s_start = S[s : s + size][start_token_masks[s : s + size]]
+ s_end = S[s : s + size][end_token_masks[s : s + size]]
+
+ p_start = torch.matmul(q[i], s_start.T).sum(1).softmax(0)
+ p_end = torch.matmul(q[i], s_end.T).sum(1).softmax(0)
+
+ if p_starts is not None:
+ p_starts = torch.vstack((p_starts, p_start))
+ p_ends = torch.vstack((p_ends, p_end))
+ else:
+ p_starts = p_start
+ p_ends = p_end
+
+ return p_starts, p_ends
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/src/fsner/tokenizer_utils.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/src/fsner/tokenizer_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..7169e23dbe490d53decb69add6c9d54c1f351b5a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/fsner/src/fsner/tokenizer_utils.py
@@ -0,0 +1,102 @@
+import torch
+
+from transformers import AutoTokenizer
+
+
+class FSNERTokenizerUtils:
+ def __init__(self, pretrained_model_name_or_path):
+ self.tokenizer = AutoTokenizer.from_pretrained(pretrained_model_name_or_path)
+
+ def tokenize(self, x):
+ """
+ Wrapper function for tokenizing query and supports
+ Args:
+ x (`List[str] or List[List[str]]`):
+ List of strings for query or list of lists of strings for supports.
+ Returns:
+ `transformers.tokenization_utils_base.BatchEncoding` dict with additional keys and values for start_token_id, end_token_id and sizes of example lists for each entity type
+ """
+
+ if isinstance(x, list) and all(isinstance(_x, list) for _x in x):
+ d = None
+ for l in x:
+ t = self.tokenizer(
+ l,
+ padding="max_length",
+ max_length=384,
+ truncation=True,
+ return_tensors="pt",
+ )
+ t["sizes"] = torch.tensor([len(l)])
+ if d is not None:
+ for k in d.keys():
+ d[k] = torch.cat((d[k], t[k]), 0)
+ else:
+ d = t
+
+ d["start_token_id"] = torch.tensor(self.tokenizer.convert_tokens_to_ids("[E]"))
+ d["end_token_id"] = torch.tensor(self.tokenizer.convert_tokens_to_ids("[/E]"))
+
+ elif isinstance(x, list) and all(isinstance(_x, str) for _x in x):
+ d = self.tokenizer(
+ x,
+ padding="max_length",
+ max_length=384,
+ truncation=True,
+ return_tensors="pt",
+ )
+
+ else:
+ raise Exception(
+ "Type of parameter x was not recognized! Only `list of strings` for query or `list of lists of"
+ " strings` for supports are supported."
+ )
+
+ return d
+
+ def extract_entity_from_scores(self, query, W_query, p_start, p_end, thresh=0.70):
+ """
+ Extracts entities from query and scores given a threshold.
+ Args:
+ query (`List[str]`):
+ List of query strings.
+ W_query (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of query sequence tokens in the vocabulary.
+ p_start (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Scores of each token as being start token of an entity
+ p_end (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Scores of each token as being end token of an entity
+ thresh (`float`):
+ Score threshold value
+ Returns:
+ A list of lists of tuples(decoded entity, score)
+ """
+
+ final_outputs = []
+ for idx in range(len(W_query["input_ids"])):
+ start_indexes = end_indexes = range(p_start.shape[1])
+
+ output = []
+ for start_id in start_indexes:
+ for end_id in end_indexes:
+ if start_id < end_id:
+ output.append(
+ (
+ start_id,
+ end_id,
+ p_start[idx][start_id].item(),
+ p_end[idx][end_id].item(),
+ )
+ )
+
+ output.sort(key=lambda tup: (tup[2] * tup[3]), reverse=True)
+ temp = []
+ for k in range(len(output)):
+ if output[k][2] * output[k][3] >= thresh:
+ c_start_pos, c_end_pos = output[k][0], output[k][1]
+ decoded = self.tokenizer.decode(W_query["input_ids"][idx][c_start_pos:c_end_pos])
+ temp.append((decoded, output[k][2] * output[k][3]))
+
+ final_outputs.append(temp)
+
+ return final_outputs
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..f685a512509f0deafbf2b78be0aa917e5dca5655
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/README.md
@@ -0,0 +1,100 @@
+
+# Information Gain Filtration(IGF)
+
+Authors @Tuko @mraunak
+
+This folder contains the code how to implement IGF for finetuning on GPT-2.
+
+## What is IGF?
+
+Here we present a general fine-tuning method that we call information gain filtration for improving the overall training efficiency and final
+performance of language model fine-tuning(see paper below). The method is an alternative fine-tuning method that trains
+a secondary model (e.g., a simple convolutional network) to predict the amount of information
+gained over a given pre-trained model. The secondary model is lightweight and trained to
+predict the Information Gain measure. Information Gain is defined as the change in a loss
+function for a model before and after an SGD update with a sample (Equation X in the paper).
+A small subset of the training set named the “objective” set, is used to measure information
+gain on the pre-trained model, and consequently to train the secondary model. After
+training, the model is used for filtering samples for the fine-tuning process. Therefore,
+a high information gain value would suggest a sample is informative, whereas a low value
+would suggest a non-informative sample that should be filtered out. Thus, a thresholding
+strategy is defined to select informative samples. With such a strategy, samples are filtered
+and once enough samples are selected to form a mini-batch and a usual fine-tuning/optimization
+step is applied. The filtration process is repeated until the fine-tuning process is over.
+
+Paper [Selecting Informative Contexts Improves Language Model Finetuning](https://arxiv.org/abs/2005.00175)
+
+# Results
+
+Several experiments were conducted to show the robustness of the IGF method versus the
+standard fine-tuning process. For example, we achieve a median perplexity of 54.0 on the
+Books dataset compared to 57.3 for standard fine-tuning on GPT-2 Small. The code was
+implemented using the Transformers library and Pytorch. While the method may seem more
+expensive, we saw enough evidence that it may lead to a performance benefit in the final models.
+
+
+
+Figure 1: Comparing IGF to Standard Fine-tuning:
+IGF with constant (p < 10−3 , t-test) and shifting(p < 10−6 , t-test) thresholding significantly outperform standard fine-tuning. The left-hand figure shows
+test-set perplexity after each fine-tuning batch, averaged over 50 runs (error bars denote ± one standard error). The right-hand figure shows the perplexity of each
+method after 60 batches. IGF with shifting thresholding (red) clearly improves over standard batched fine-tuning with Adam
+
+## How to use this project?
+
+To fine-tune a transformer model with IGF on a language modeling task, use the following script:
+
+- `model_name_or_path`: Path to pretrained model or model identifier from huggingface.co/models
+- `data_file`: A jbl file containing tokenized data which can be split as objective dataset,
+ train_dataset and test_dataset
+- `igf_data_file`: A jbl file containing the context and information gain pairs to train secondary learner.
+- `context_len`: The maximum total input sequence length after tokenization. Sequences longer
+ than this will be truncated, sequences shorter will be padded.
+- `size_objective_set`: Number of articles that are long enough to be used as our objective set"
+- `min_len`: The minimum length of the article to be used as objective set
+- `trim`: Truncate the example if it exceeds context length
+- `eval_freq`: Secondary model evaluation can be triggered at eval_freq
+- `max_steps`: To calculate training epochs
+- `number`: The number of examples split to be used as objective_set/test_data
+- `secondary_learner_batch_size`: The batch size of training data for secondary learner
+- `secondary_learner_max_epochs`: The number of epochs to train secondary learner
+- `recopy_model`: Reset the model to the original pretrained GPT-2 weights after each iteration
+- `eval_interval`: Decay the selectivity of our secondary learner filter from"
+ 1 standard deviation above average to 1 below average after eval_interval(10) batches"
+
+
+```python
+python run_clm_igf.py\
+--model_name_or_path "openai-community/gpt2" \
+--data_file="data/tokenized_stories_train_wikitext103" \
+--igf_data_file="data/IGF_values" \
+--context_len 32 \
+--size_objective_set 100 \
+--min_len 1026 \
+--trim True \
+--eval_freq 100 \
+--max_steps 1000 \
+--secondary_learner_batch_size 128 \
+--secondary_learner_max_epochs 15 \
+--number 100 \
+--recopy_model \
+--eval_interval 10 \
+```
+
+## Citation
+
+If you find the resource useful, please cite the following paper
+
+```bibtex
+@inproceedings{antonello-etal-2021-selecting,
+ title = "Selecting Informative Contexts Improves Language Model Fine-tuning",
+ author = "Antonello, Richard and Beckage, Nicole and Turek, Javier and Huth, Alexander",
+ booktitle = "Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing (Volume 1: Long Papers)",
+ month = aug,
+ year = "2021",
+ address = "Online",
+ publisher = "Association for Computational Linguistics",
+ url = "https://aclanthology.org/2021.acl-long.87",
+ doi = "10.18653/v1/2021.acl-long.87",
+ pages = "1072--1085",
+}
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/igf/__init__.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/igf/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/igf/igf.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/igf/igf.py
new file mode 100644
index 0000000000000000000000000000000000000000..4c5aefd9584e16468d303372018ca66d7fc030b1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/igf/igf.py
@@ -0,0 +1,416 @@
+# Copyright 2022 - Intel Corp. All rights reserved.
+# Authors: Mayank Kumar Raunak, Javier Turek, Nicole Backage
+
+import copy
+import logging
+import random
+
+import joblib
+import numpy as np
+import torch
+import torch.nn as nn
+from torch.utils.data import DataLoader
+from tqdm import tqdm
+
+from transformers import AdamW, GPT2LMHeadModel, get_linear_schedule_with_warmup
+
+
+logger = logging.getLogger(__name__)
+
+
+def set_seed(seed):
+ """
+ For reproducible training
+
+ Args:
+ seed: A seed for reproducible training
+
+ """
+ random.seed(seed)
+ np.random.seed(seed)
+ torch.manual_seed(seed)
+ torch.cuda.manual_seed_all(seed)
+
+
+def compute_perplexity(model, test_data, context_len):
+ """
+ Computes perplexity of the transformer model on data in test_data
+
+ Args:
+ model: Pre-trained GPT2 model
+ test_data: Data on which perplexity calculation is required
+ context_len: The maximum total input sequence length after tokenization. Sequences longer
+ than this will be truncated, sequences shorter will be padded
+
+ Returns:
+ Perplexity on input test data
+
+ """
+
+ model.eval()
+ device = next(model.parameters()).device
+ eval_batch_size = 1
+ context = torch.zeros((eval_batch_size, context_len), dtype=torch.long, device=device)
+ eval_dataloader = DataLoader(test_data, shuffle=False, batch_size=eval_batch_size)
+ eval_loss = torch.zeros(1, device=device)
+ nb_eval_examples = 0
+ for batch in eval_dataloader:
+ batch.to(device)
+ # pad
+ context.zero_()
+ for i in range(eval_batch_size):
+ context[i, :] = batch[i]
+ outputs = model(context, labels=context)
+ eval_loss += outputs[0].sum().item()
+ nb_eval_examples += batch.size(0)
+ eval_loss = eval_loss / nb_eval_examples
+ perplexity = torch.exp(eval_loss)
+ model.train()
+ return perplexity
+
+
+def load_gpt2(model_name="openai-community/gpt2"):
+ """
+ load original openai-community/gpt2 and save off for quicker loading
+
+ Args:
+ model_name: GPT-2
+
+ Returns:
+ GPT-2 model
+
+ """
+
+ model = GPT2LMHeadModel.from_pretrained(model_name, output_hidden_states=True)
+ torch.save(model.state_dict(), model_name + "local.pt")
+ return model
+
+
+def recopy_gpt2(orig_model, device, max_steps):
+ """
+ Reset the model to the original pretrained GPT-2 weights after each iteration
+
+ Args:
+ orig_model: Original pretrained GPT-2 model imported from Transformers library
+ device: CPU/GPU
+ max_steps: number of training steps
+
+ Returns:
+ Original PreTrained GPT-2 model,
+ lm_optimizer: Adam optimizer with Decoupled weight decay
+ lm_scheduler: linear scheduler with the appropriate schedule
+
+ """
+ model = copy.deepcopy(orig_model)
+ model.to(device)
+
+ no_decay = ["bias", "LayerNorm.weight"]
+ optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
+ "weight_decay": 0.0,
+ },
+ {"params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)], "weight_decay": 0.0},
+ ]
+ lm_optimizer = AdamW(optimizer_grouped_parameters, lr=5e-5, eps=1e-8)
+ lm_scheduler = get_linear_schedule_with_warmup(lm_optimizer, 0, max_steps)
+ torch.cuda.empty_cache()
+ return model, lm_optimizer, lm_scheduler
+
+
+def intermittent_save(contexts, real_perps, past_perps, filename):
+ """
+ save the perplexity differences to filename
+
+ Args:
+ contexts: Example on which the perplexity is calculated
+ real_perps: Perplexity after back-propagating on the selected context
+ past_perps: Perplexity of model before training on the context
+ filename: File to store perplexity differences
+
+ Returns:
+ file with perplexity differences
+
+ """
+ # save the perplexity differences to filename
+ avg = np.array(real_perps).mean()
+ std = np.array(real_perps).std()
+ perp_diff = (real_perps - avg) / std
+ data_final = list(zip(contexts, perp_diff, past_perps))
+ joblib.dump(data_final, filename)
+
+
+def collect_objective_set(
+ model,
+ orig_perp,
+ context_len,
+ train_data,
+ objective_set,
+ max_steps,
+ device,
+ filename="dev.jbl",
+ recopy_model=recopy_gpt2,
+):
+ """
+ Collect individual IGF values from pre-trained transformer model
+ max_steps samples of training data to train secondary model
+
+ Args:
+ model: Pre-trained GPT2 model
+ orig_perp: Perplexity of original pretrained GPT-2 model
+ context_len: The maximum total input sequence length after tokenization. Sequences longer
+ than this will be truncated, sequences shorter will be padded
+ train_data: Data to train model
+ objective_set: Contexts used to create (X,IG(X)) pairs which is the training data for secondary learner
+ max_steps: To calculate training epochs of model
+ device: GPU/CPU
+ filename: To store intermediate perplexity differences
+ recopy_model: Reset the model to the original pretrained GPT-2 weights after each iteration
+
+ Returns:
+ file stored intermediate perplexity differences in intermediate stages
+
+ """
+
+ # initialize variables to record relevant information
+ contexts = []
+ real_perps = []
+ past_perps = []
+
+ # Initialize the transformer model
+ orig_model = copy.deepcopy(model)
+ orig_model.to(device="cpu")
+ torch.cuda.empty_cache()
+
+ # Compute perplexity of initial transformer model for comparison
+ model.train()
+ model, lm_optimizer, lm_scheduler = recopy_model(orig_model, device, max_steps)
+
+ for step in tqdm(range(max_steps)):
+ context = torch.zeros((1, context_len), dtype=torch.long, device=device)
+ story = random.choice(train_data)
+ start = random.randint(0, len(story[0]) - context_len - 1)
+ context[0, :] = story[0][start : start + context_len]
+ lm_optimizer.zero_grad()
+ outputs = model(context, labels=context)
+ lm_loss = outputs[0]
+ past_perp = compute_perplexity(model, context, context_len)
+ model.train()
+ lm_loss.backward()
+ # Do LM backprop
+ torch.nn.utils.clip_grad_norm_(model.parameters(), 3.0)
+ lm_optimizer.step()
+ lm_scheduler.step() # Update learning rate schedule
+
+ # Compute perplexity after back-propagating on the selected context
+ real_perp = compute_perplexity(model, objective_set, context_len)
+
+ # Periodically save the stored (X, IG(X)) pairs
+ if step % 1000 == 0 and step > 1:
+ intermittent_save(contexts, real_perps, past_perps, filename)
+
+ # Reset the pretrained model to the original pretrained GPT-2 weights after each iteration
+ model, lm_optimizer, lm_scheduler = recopy_model(orig_model, device, max_steps)
+
+ past_perps.append(past_perp.item())
+ real_perps.append(orig_perp - real_perp.item())
+ contexts.append(np.array(context.cpu()))
+
+ intermittent_save(contexts, real_perps, past_perps, filename)
+
+
+def generate_datasets(
+ context_len, file="data/tokenized_stories_train_wikitext103.jbl", number=100, min_len=1026, trim=True
+):
+ """
+ Generate objective set and training set
+
+ Args:
+ context_len: The maximum total input sequence length after tokenization. Sequences longer
+ than this will be truncated, sequences shorter will be padded
+ file: Tokenized data split into training set and objective set
+ number: size of objective dataset
+ min_len: minimum length of a context in objective set
+ trim: If True truncate the context if it exceeds context length
+
+ Returns:
+ Generated objective set and training data
+
+
+ """
+ # Generate objective set and training set
+ # Designate the first number (100) articles that are long enough to be used
+ # as our objective set, rest (that are long enough) are training data for
+ # secondary learner
+
+ data = joblib.load(file)
+ print("data loaded")
+ objective_set = []
+ if trim:
+ for i, example in enumerate(data):
+ if len(example[0]) > min_len:
+ start = random.randint(0, len(example[0]) - context_len - 1)
+ objective_set.append(example[0, start : start + context_len])
+ if len(objective_set) >= number:
+ break
+ train_data = []
+ for j in range(i + 1, len(data)):
+ if len(data[j][0]) > min_len:
+ train_data.append(data[j])
+ else:
+ objective_set = data[0:number]
+ train_data = data[number:]
+
+ joblib.dump(objective_set, "objective_set.jbl")
+ print("objective set saved")
+ return train_data, objective_set
+
+
+def train_secondary_learner(
+ secondary_learner, train_dataset, max_epochs, batch_size, eval_freq=50, igf_model_path="secondary_learner.pt"
+):
+ """
+ Train the secondary learner (igf_model)
+
+ Args:
+ secondary_learner: secondary learner
+ train_dataset: data to train secondary learner
+ max_epochs: number of epochs to train secondary learner
+ batch_size: batch size of training data of secondary learner
+ eval_freq: secondary model evaluation can be triggered at eval_freq
+ igf_model_path: path to store trained secondary learner
+
+ Returns:
+ Trained secondary learner
+
+ """
+ device = torch.device("cuda:0" if torch.cuda.is_available() else "cpu")
+ # We will use the first 512 pairs from our dataset as a test set for
+ # our secondary learner and the rest to train
+ test_dataset = train_dataset[:512]
+ train_dataset = train_dataset[512:]
+ train_dataloader = DataLoader(train_dataset, shuffle=True, batch_size=batch_size)
+ test_dataloader = DataLoader(test_dataset, shuffle=False, batch_size=batch_size)
+
+ # secondary learner model set up
+ loss = nn.MSELoss()
+ test_loss = nn.MSELoss(reduction="sum")
+ secondary_learner.to(device)
+ q_optimizer = torch.optim.Adam(secondary_learner.parameters(), lr=0.00001)
+ secondary_learner.train()
+
+ # TODO in original code this is written as number of actual batches seen
+ # not number of items seen but other places it is number of items instead.
+ # improve consistency! changed this to epochs for clarity
+ best_test_loss = float("inf")
+ # Iterate through batches until we've used max_steps batches
+ for epoch in range(int(max_epochs)):
+ tr_q_loss = 0.0
+ secondary_learner.train()
+ for step, batch in enumerate(train_dataloader):
+ context = batch[0].to(device)
+ real_q = batch[1].to(device)
+ predicted_q = secondary_learner(context)
+ q_optimizer.zero_grad()
+ q_loss = loss(predicted_q, real_q.float())
+ q_loss.backward()
+ q_optimizer.step()
+ tr_q_loss += q_loss.item()
+
+ # model trains fairly quickly so we won't wait for a full epoch
+ # eval is triggered at eval_freq and end of epochs
+ if (step % eval_freq == 0 and step > 0) or ((step + 1) == len(train_dataloader)):
+ tr_loss = tr_q_loss / (step + 1)
+
+ secondary_learner.eval()
+ q_loss2 = 0.0
+ sum_q2 = 0.0
+ predicted = []
+ actual = []
+ # Compute performance of the secondary learner after this batch
+ for step2, batch2 in enumerate(test_dataloader):
+ features2 = batch2[0].to(device)
+ real_q2 = batch2[1].to(device)
+ predicted_q2 = secondary_learner(features2)
+ q_loss2 += test_loss(predicted_q2, real_q2).item()
+ sum_q2 += torch.sum(predicted_q2).item()
+ for ei, i in enumerate(predicted_q2.cpu().detach().numpy()):
+ predicted.append(i.item())
+ for ei, i in enumerate(real_q2.cpu().detach().numpy()):
+ actual.append(i.item())
+
+ q_loss2 /= len(test_dataset)
+ print(
+ "Epoch: ",
+ epoch,
+ "step: ",
+ step,
+ "Avg. q:",
+ sum_q2 / len(test_dataset),
+ "Train Loss: ",
+ tr_loss,
+ "Test Loss: ",
+ q_loss2,
+ )
+ if q_loss2 < best_test_loss:
+ joblib.dump((predicted, actual), "pred_vs_actual.jbl")
+ torch.save(secondary_learner.state_dict(), igf_model_path)
+ best_test_loss = q_loss2
+
+ secondary_learner.train()
+ return secondary_learner
+
+
+class SecondaryLearner(nn.Module):
+ """
+ Our secondary learner
+ """
+
+ def __init__(self, model):
+ """
+ We use a simple convolutional network as our secondary learner
+
+ Args:
+ model: Pre-trained GPT2 model
+ """
+ # embeddings are from the pretrained model
+ super(SecondaryLearner, self).__init__()
+ self.embeddings = model.transformer.wte
+ self.embeddings.weight = copy.deepcopy(model.transformer.wte.weight)
+ self.conv = nn.Conv1d(self.embeddings.weight.size(1), 256, 3, padding=1)
+ self.fc = nn.Sequential(nn.Linear(256, 32), nn.Dropout(p=0.1), nn.Linear(32, 32), nn.Linear(32, 1))
+
+ def forward(self, context):
+ """
+ Forward pass through the secondary learner
+
+ Args:
+ context: Context input to the secondary learner
+
+ Returns:
+ tensor after squeeze operation
+
+ """
+ pooled = torch.max(self.conv(self.embeddings(context).squeeze(1).transpose(1, 2)), 2)[0]
+ qs = self.fc(pooled)
+ return qs.squeeze(1)
+
+ @classmethod
+ def from_pretrained(cls, state_path, model):
+ """
+ Load the secondary learner
+
+ Args:
+ state_path: Path to save secondary learner
+ model: Pretrained GPT-2
+
+ Returns:
+ secondary learner
+ """
+
+ secondary_learner = cls(model) # this calls __init__
+ state_dict = torch.load(state_path)
+ secondary_learner.load_state_dict(state_dict)
+ secondary_learner.embeddings = model.transformer.wte
+ secondary_learner.embeddings.weight = copy.deepcopy(model.transformer.wte.weight)
+ return secondary_learner
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..2aa3227637c888310bf557baa3b952a5aa680248
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/requirements.txt
@@ -0,0 +1,6 @@
+matplotlib
+numpy>=1.17.2
+joblib>=0.13.2
+scipy
+torch>=1.10.1
+transformers>=3.5
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/result_igf.png b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/result_igf.png
new file mode 100644
index 0000000000000000000000000000000000000000..4cb14d28dda18da032311e8f9829010e8d9f27eb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/result_igf.png
@@ -0,0 +1,3 @@
+version https://git-lfs.github.com/spec/v1
+oid sha256:6e2be58929bc08cf8a79f51a956c3fcaa1ce0dd68b51be09866403fe380e1949
+size 34410
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/run_clm_igf.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/run_clm_igf.py
new file mode 100644
index 0000000000000000000000000000000000000000..74973309c4e16b4aa6fc6e3ba4ed5e1e95a86ee0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/information-gain-filtration/run_clm_igf.py
@@ -0,0 +1,450 @@
+# Copyright 2022 - Intel Corp. All rights reserved.
+# Authors: Mayank Kumar Raunak, Javier Turek, Nicole Beckage
+
+"""
+Implementation of a new method for fine-tuning transformer models that we call
+Information Gain Filtration 'IGF' on WikiText data set and compared the results
+with the standard fine-tuning method
+
+Steps followed in the code:
+
+1) Generate a objective dataset of pairs (X, IG(X)). IG(X)--Informativeness of context 'X'.
+Our IG (information gain) model is learning to predict the ‘informativeness’ of a particular
+context. Informativeness is the change in metric between the model’s accuracy on an
+objective set before and after seeing that context. For casual language modeling, the
+metric is perplexity.
+
+2) A secondary learner is trained to infer a function approximation for IG using the dataset
+created in (1).
+
+3) The learner created in (2) is used to inform the fine-tuning process and filter out low informative samples.
+
+Last, a plot is generated to compare the performance of IGF to standard fine-tuning without any filtering
+
+"""
+
+# Prerequisite libraries:
+
+import argparse
+import random
+
+import joblib
+import numpy as np
+import torch
+from igf.igf import (
+ SecondaryLearner,
+ collect_objective_set,
+ compute_perplexity,
+ generate_datasets,
+ load_gpt2,
+ recopy_gpt2,
+ set_seed,
+ train_secondary_learner,
+)
+from torch.utils.data import DataLoader, RandomSampler
+
+from transformers import GPT2LMHeadModel
+
+
+def generate_n_pairs(
+ context_len=32,
+ max_steps=10,
+ size_objective_set=100,
+ min_len=1026,
+ trim=True,
+ data_file="data/tokenized_stories_train_wikitext103.jbl",
+ igf_data_file="igf_context_pairs.jbl",
+):
+ """
+ Collecting *n* pairs for training the secondary learner
+ Args:
+ context_len: The maximum total input sequence length after tokenization. Sequences longer
+ than this will be truncated, sequences shorter will be padded
+ max_steps: To calculate training epochs of secondary learner
+ size_objective_set: size of objective data set used to create (X,IG(X)) pairs which is the training data for secondary learner
+ min_len: The minimum length of the article to be used as objective set
+ trim: If True truncate the context if it exceeds context length
+ data_file: Tokenized data set split for training and evaluation of model
+ igf_data_file: file to store (I,IG(X)) paired data set to train secondary learner
+
+ Returns:
+ Data stored in igf_data_file
+
+ """
+ # generates same data everytime
+ set_seed(3)
+ # generate train_data and objective_set
+ train_data, objective_set = generate_datasets(
+ context_len, data_file, number=size_objective_set, min_len=1026, trim=True
+ )
+ # keeps model same across runs
+ set_seed(4)
+ # model, lm_optimizer, lm_scheduler = recopy_gpt2(model, device, max_steps) # store original model weights
+ # can we train on GPU?
+ device = torch.device("cuda:0" if torch.cuda.is_available() else "cpu")
+
+ # load pretrained model
+ model = load_gpt2("openai-community/gpt2").to(device)
+ print("computing perplexity on objective set")
+ orig_perp = compute_perplexity(model, objective_set, context_len).item()
+ print("perplexity on objective set:", orig_perp)
+
+ # collect igf pairs and save to file demo.jbl
+ collect_objective_set(model, orig_perp, context_len, train_data, objective_set, max_steps, device, igf_data_file)
+
+ # clean up, delete model and data we don't need anymore
+ del model, train_data, objective_set
+ torch.cuda.empty_cache()
+
+
+def training_secondary_learner(
+ secondary_learner_train_data,
+ secondary_learner_max_epochs=15,
+ secondary_learner_batch_size=128,
+ eval_freq=100,
+ igf_model_path="igf_model.pt",
+):
+ """
+ Train the secondary learner
+
+ Args:
+ secondary_learner_train_data: Data set with (X,IG(X)) pairs to train secondary learner where IG(X) - measure of informativeness and X- context
+ secondary_learner_max_epochs: Number of epochs to train secondary learner
+ secondary_learner_batch_size: Batch size to train secondary learner
+ eval_freq (object): secondary model evaluation can be triggered at eval_freq
+ igf_model_path: path to store trained secondary learner
+
+ Returns:
+ Trained secondary learner
+ """
+
+ set_seed(42)
+
+ # Load pre-trained model
+ model = GPT2LMHeadModel.from_pretrained("openai-community/gpt2")
+
+ # Initialize secondary learner to use embedding weights of model
+ secondary_learner = SecondaryLearner(model)
+
+ # Train secondary learner
+ secondary_learner = train_secondary_learner(
+ secondary_learner,
+ secondary_learner_train_data,
+ max_epochs=secondary_learner_max_epochs,
+ batch_size=secondary_learner_batch_size,
+ eval_freq=100,
+ igf_model_path=igf_model_path,
+ )
+
+ del model, secondary_learner_train_data
+ torch.cuda.empty_cache()
+
+ return secondary_learner
+
+
+def finetune(
+ model,
+ train_dataset,
+ test_dataset,
+ context_len=32,
+ max_steps=1000,
+ batch_size=16,
+ threshold=1.0,
+ recopy_model=recopy_gpt2,
+ secondary_learner=None,
+ eval_interval=10,
+ finetuned_model_name="openai-community/gpt2_finetuned.pt",
+):
+ """
+ fine-tune with IGF if secondary_learner is not None, else standard fine-tuning
+
+ Args:
+ model: pre-trained GPT-2 model
+ train_dataset: Data set to train GPT-2 model
+ test_dataset: Evaluate GPT-2 model
+ context_len: The maximum total input sequence length after tokenization. Sequences longer
+ than this will be truncated, sequences shorter will be padded
+ max_steps: To calculate training epochs
+ batch_size: Batch size to train GPT-2 model
+ threshold: The threshold value used by secondary learner to filter the train_data and allow only"
+ informative data as input to the model
+ recopy_model: Reset the model to the original pretrained GPT-2 weights after each iteration
+ secondary_learner: Selection of IGF as fine-tuning method if not None
+ eval_interval: number of batches after which decay the selectivity of our secondary learner filter from
+ 1 standard deviation above average to 1 below average
+ fine-tuned_model_name: name of the final final-tuned GPT-2 model
+
+ Returns:
+ Fine-tuned GPT-2 model
+
+ """
+
+ device = torch.device("cuda:0" if torch.cuda.is_available() else "cpu")
+ train_sampler = RandomSampler(train_dataset)
+ train_dataloader = DataLoader(train_dataset, sampler=train_sampler)
+
+ num_train_epochs = max_steps // (len(train_dataset)) + 1
+ global_step = 0
+ context = torch.zeros((1, context_len), dtype=torch.long, device=device)
+ model, lm_optimizer, lm_scheduler = recopy_model(model, device, max_steps)
+
+ model.train()
+ if secondary_learner is not None:
+ secondary_learner.to(device)
+ secondary_learner.eval()
+ contexts = []
+ examples = 0
+
+ observed_qs = []
+ test_perps = []
+
+ # Compute the performance of the transformer model at the beginning
+ real_perp = compute_perplexity(model, test_dataset, context_len)
+ test_perps.append(real_perp)
+ print("Test perplexity, step", global_step, ":", real_perp)
+ for epoch in range(int(num_train_epochs)):
+ for step, example in enumerate(train_dataloader):
+ torch.cuda.empty_cache()
+ start = random.randint(0, example.size(2) - context_len - 1)
+ context[0, :] = example[0, 0, start : start + context_len]
+ lm_optimizer.zero_grad()
+ outputs = model(context, labels=context)
+ do_backprop = True
+
+ if secondary_learner is not None:
+ predicted_q = secondary_learner.forward(
+ torch.tensor(context, dtype=torch.long, device=device).unsqueeze(0)
+ )[0].item()
+ observed_qs.append(float(predicted_q))
+
+ # Here we implement the simple non-constant threshold for the predicted IG(X) value
+ # We will decay the selectivity of our secondary learner filter from
+ # 1 standard deviation above average to 1 below average after 10 batches.
+
+ if global_step == 10:
+ threshold = -1
+ if predicted_q < threshold:
+ do_backprop = False
+
+ # If we passed the filter, add the context to the batch!
+ if do_backprop:
+ contexts.append(np.array(context.cpu()))
+ lm_loss = outputs[0]
+ lm_loss.backward()
+ examples += 1
+
+ del outputs
+
+ # Once the batch is filled with enough contexts, backprop on the batch.
+ if examples == batch_size:
+ torch.cuda.empty_cache()
+ examples = 0
+ # Do LM backprop
+ torch.nn.utils.clip_grad_norm_(model.parameters(), 3.0)
+ lm_optimizer.step()
+ lm_scheduler.step() # Update learning rate schedule
+ global_step += 1
+ # Compute the performance of the transformer model at this batch
+ if global_step % eval_interval == 0:
+ real_perp = compute_perplexity(model, test_dataset, context_len)
+ test_perps.append(real_perp)
+
+ print("Test perplexity, step", global_step, ":", real_perp)
+ # Break out of the loop after 60 batches
+ if max_steps > 0 and global_step > 60:
+ break
+ if max_steps > 0 and global_step > 60:
+ break
+
+ # save finetuned transformer model
+ torch.save(model.state_dict(), finetuned_model_name)
+ torch.cuda.empty_cache()
+ # Do some cleaning up so we can reinitialize for the next run of this function
+ del lm_optimizer
+ del lm_scheduler
+ return model
+
+
+def main():
+ parser = argparse.ArgumentParser(description="Fine-tune a transformer model with IGF on a language modeling task")
+
+ # Required parameters
+ parser.add_argument(
+ "--data_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The input data dir. Should contain data files for WikiText.",
+ )
+ parser.add_argument(
+ "--model_name_or_path",
+ default=None,
+ type=str,
+ required=True,
+ help="Path to pretrained model or model identifier from huggingface.co/models",
+ )
+ parser.add_argument(
+ "--data_file",
+ type=str,
+ default=None,
+ help=(
+ "A jbl file containing tokenized data which can be split as objective dataset, "
+ "train_dataset and test_dataset."
+ ),
+ )
+
+ parser.add_argument(
+ "--igf_data_file",
+ type=str,
+ default=None,
+ help="A jbl file containing the context and information gain pairs to train secondary learner.",
+ )
+
+ parser.add_argument(
+ "--output_dir",
+ default=None,
+ type=str,
+ required=True,
+ help="The output directory where the final fine-tuned model is stored.",
+ )
+
+ parser.add_argument(
+ "--tokenizer_name",
+ default=None,
+ type=str,
+ help="Pretrained tokenizer name or path if not the same as model_name",
+ )
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+
+ parser.add_argument(
+ "--context_len",
+ default=32,
+ type=int,
+ help=(
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ ),
+ )
+
+ parser.add_argument(
+ "--size_objective_set",
+ default=100,
+ type=int,
+ help="number of articles that are long enough to be used as our objective set",
+ )
+ parser.add_argument(
+ "--eval_freq", default=100, type=int, help="secondary model evaluation is triggered at eval_freq"
+ )
+
+ parser.add_argument("--max_steps", default=1000, type=int, help="To calculate training epochs")
+
+ parser.add_argument(
+ "--secondary_learner_batch_size",
+ default=128,
+ type=int,
+ help="batch size of training data for secondary learner",
+ )
+
+ parser.add_argument(
+ "--batch_size",
+ default=16,
+ type=int,
+ help="batch size of training data of language model(openai-community/gpt2) ",
+ )
+
+ parser.add_argument(
+ "--eval_interval",
+ default=10,
+ type=int,
+ help=(
+ "decay the selectivity of our secondary learner filter from "
+ "1 standard deviation above average to 1 below average after 10 batches"
+ ),
+ )
+
+ parser.add_argument(
+ "--number", default=100, type=int, help="The number of examples split to be used as objective_set/test_data"
+ )
+
+ parser.add_argument(
+ "--min_len", default=1026, type=int, help="The minimum length of the article to be used as objective set"
+ )
+
+ parser.add_argument(
+ "--secondary_learner_max_epochs", default=15, type=int, help="number of epochs to train secondary learner"
+ )
+
+ parser.add_argument("--trim", default=True, type=bool, help="truncate the example if it exceeds context length")
+
+ parser.add_argument(
+ "--threshold",
+ default=1.0,
+ type=float,
+ help=(
+ "The threshold value used by secondary learner to filter the train_data and allow only"
+ " informative data as input to the model"
+ ),
+ )
+
+ parser.add_argument(
+ "--finetuned_model_name", default="openai-community/gpt2_finetuned.pt", type=str, help="finetuned_model_name"
+ )
+
+ parser.add_argument(
+ "--recopy_model",
+ default=recopy_gpt2,
+ type=str,
+ help="Reset the model to the original pretrained GPT-2 weights after each iteration",
+ )
+
+ # function calls
+ # Collecting *n* pairs of context and information gain(X, IG(X)) for training the secondary learner
+ generate_n_pairs(
+ context_len=32,
+ max_steps=10,
+ size_objective_set=100,
+ min_len=1026,
+ trim=True,
+ data_file="data/tokenized_stories_train_wikitext103.jbl",
+ igf_data_file="igf_context_pairs.jbl",
+ )
+
+ # Load train data for secondary learner
+ secondary_learner_train_data = joblib.load("data/IGF_values.jbl")
+
+ # Train secondary learner
+ secondary_learner = training_secondary_learner(
+ secondary_learner_train_data,
+ secondary_learner_max_epochs=15,
+ secondary_learner_batch_size=128,
+ eval_freq=100,
+ igf_model_path="igf_model.pt",
+ )
+
+ # load pretrained openai-community/gpt2 model
+ model = GPT2LMHeadModel.from_pretrained("openai-community/gpt2")
+ set_seed(42)
+
+ # Generate train and test data to train and evaluate openai-community/gpt2 model
+ train_dataset, test_dataset = generate_datasets(
+ context_len=32, file="data/tokenized_stories_train_wikitext103.jbl", number=100, min_len=1026, trim=True
+ )
+
+ # fine-tuning of the openai-community/gpt2 model using igf (Information Gain Filtration)
+ finetune(
+ model,
+ train_dataset,
+ test_dataset,
+ context_len=32,
+ max_steps=1000,
+ batch_size=16,
+ threshold=1.0,
+ recopy_model=recopy_gpt2,
+ secondary_learner=secondary_learner,
+ eval_interval=10,
+ finetuned_model_name="openai-community/gpt2_finetuned.pt",
+ )
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/HOW_TO_PROPOSE_PROJECT.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/HOW_TO_PROPOSE_PROJECT.md
new file mode 100644
index 0000000000000000000000000000000000000000..08e05f38931943134ac8c4457ded19da7d41abc4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/HOW_TO_PROPOSE_PROJECT.md
@@ -0,0 +1,109 @@
+# How to propose a Flax/JAX + Transformers project
+
+Great that you've opened this document!
+While we at 🤗 are proposing a couple of projects, we strongly
+believe that the community can come up with much more **creative**, **fun**, and
+**impactful** projects on their own. This being said, we are really looking forward
+to seeing your project proposal!
+
+## What a project should be about
+
+The proposed project should fall into the machine learning fields of **Natural Language Processing (NLP)** and/or **Computer Vision (CV)** (possibly also **Speech Recognition (ASR)** depending on whether Speech Recognition models are available in Flax in due time) and aim at solving a specific task.
+Possible tasks can belong to:
+
+ * text classification
+ * text generation
+ * image recognition
+ * image processing
+ * image captioning
+ * audio classification
+ * and other tasks you can think of!
+
+The clearer a task is defined, the better your project proposal is.
+*E.g.* "Using a T5 model to learn grammar correction in French" or "Adapting a pre-trained CLIP model for zero-shot image classification in Spanish" are **well-defined and clear** project proposals, while something like "Train a language model" or "Image classification" are **too vague**.
+
+There is no limit to your creativity as long as the project is feasible and ethical.
+The more creative & specific your project proposal, the more interesting it will be,
+and the more likely will you find motivated team members to work on your project!
+To get an idea of how to formulate your project proposals, you can browse through
+existing project proposals on the [forum](https://discuss.huggingface.co/c/flax-jax-projects/22).
+
+## How to submit a project proposal
+
+First, you should make sure that you are [logged in](https://huggingface.co/login?sso=bm9uY2U9OTRlNjZjZmZhYjMwMmJmMWMyYjc5MmFiMTMyMzY5ODYmcmV0dXJuX3Nzb191cmw9aHR0cHMlM0ElMkYlMkZkaXNjdXNzLmh1Z2dpbmdmYWNlLmNvJTJGc2Vzc2lvbiUyRnNzb19sb2dpbg%3D%3D&sig=429ad8924bcb33c40f9823027ea749abb55d393f4f58924f36a2dba3ab0a48da) with your Hugging Face account on the forum.
+
+Second, make sure that your project idea doesn't already exist by checking [existing projects](https://discuss.huggingface.co/c/flax-jax-projects/22).
+If your project already exists - great! This means that you can comment and improve
+the existing idea and join the project to form a team! If your project idea already
+exists for a different language, feel free to submit the same project idea, just in
+a different language.
+
+Third, having ensured that your project doesn't exist, click on the *"New Topic"*
+button on the [Flax/JAX Projects Forum category](https://discuss.huggingface.co/c/flax-jax-projects/22) to create a new project proposal.
+
+Fourth, make sure that your project proposal includes the following information:
+
+1. *A clear description of the project*
+2. *In which language should the project be conducted?* English, German, Chinese, ...? It can also be a multi-lingual project
+3. *Which model should be used?* If you want to adapt an existing model, you can add the link to one of the 4000 available checkpoints in JAX [here](https://huggingface.co/models?filter=jax) If you want to train a model from scratch, you can simply state the model architecture to be used, *e.g.* BERT, CLIP, etc. You can also base your project on a model that is not part of transformers. For an overview of libraries based on JAX, you can take a look at [awesome-jax](https://github.com/n2cholas/awesome-jax#awesome-jax-). **Note** that for a project that is not based on Transformers it will be more difficult for the 🤗 team to help you. Also have a look at the section [Quickstart Flax & Jax in Transformers](https://github.com/huggingface/transformers/tree/main/examples/research_projects/jax-projects#quickstart-flax-and-jax-in-transformers) to see what model architectures are currently supported in 🤗 Transformers.
+4. *What data should be used?* It is important to state at least what kind of data you would like to use. Ideally, you can already point to publicly available data or a dataset in the 🤗 Datasets library.
+5. *Are similar training scripts available in Flax/JAX?* It would be important to find similar training scripts that already exist in Flax/JAX. *E.g.* if you are working on a Seq-to-Seq task, you can make use of the [`run_summarization_flax.py`](https://github.com/huggingface/transformers/blob/main/examples/flax/summarization/run_summarization_flax.py) script which is very similar to any seq2seq training. Also have a look at the section [Quickstart Flax & Jax in Transformers](https://github.com/huggingface/transformers/tree/main/examples/research_projects/jax-projects#quickstart-flax-and-jax-in-transformers) to see what training scripts are currently supported in 🤗 Transformers.
+6. *(Optionally) What are possible challenges?* List possible difficulties with your project. *E.g.* If you know that training convergence usually takes a lot of time, it is worth stating this here!
+7. *(Optionally) What is the desired project outcome?* - How would you like to demo your project? One could *e.g.* create a Streamlit application.
+8. *(Optionally) Links to read upon* - Can you provide any links that would help the reader to better understand your project idea?
+
+Feel free to copy-paste the following format for your project proposal and fill out the respective sections:
+
+```
+#
+
+
+
+## 2. Language
+
+The model will be trained in .
+
+## 3. Model
+
+
+
+## 4. Datasets
+
+
+
+Possible links to publicly available datasets include:
+-
+-
+-
+
+## 5. Training scripts
+
+
+
+We can make use of to train the model.>
+
+## 6. (Optional) Challenges
+
+<(Optionally) FILL ME: 6. What are possible challenges?>
+
+## 7. (Optional) Desired project outcome
+
+<(Optionally) FILL ME: 7. What is the desired project outcome? A demo?>
+
+## 8. (Optional) Reads
+
+The following links can be useful to better understand the project and
+what has previously been done.
+
+-
+-
+-
+```
+
+To see how a proposed project looks like, please have a look at submitted project
+proposals [here](https://discuss.huggingface.co/c/flax-jax-projects/22).
+
+## Will my project proposal be selected?
+
+Having submitted a project proposal, you can now promote your idea in the Slack channel `#flax-jax-community-week` to try to convince other participants to join your project!
+Once other people have joined your project, one of the organizers (`@Suzana, @valhalla, @osanseviero, @patrickvonplaten`) will officially create a team for your project and add your project to [this google sheet](https://docs.google.com/spreadsheets/d/1GpHebL7qrwJOc9olTpIPgjf8vOS0jNb6zR_B8x_Jtik/edit?usp=sharing).
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..88d8d7f9eba9269ed9659463a690b6b76d890d42
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/README.md
@@ -0,0 +1,1295 @@
+# Flax/JAX community week 🤗
+
+Welcome to the Flax/JAX community week! The goal of this week is to make compute-intensive NLP and CV projects (like pre-training BERT, GPT2, CLIP, ViT)
+practicable for a wider audience of engineers and researchers.
+To do so, we will try to teach **you** how to effectively use JAX/Flax on TPU and help you to complete a fun NLP and/or CV project in JAX/Flax during the community week.
+
+Free access to a TPUv3-8 will kindly be provided by the Google Cloud team!
+
+In this document, we list all the important information that you will need during the Flax/JAX community week.
+
+Don't forget to sign up [here](https://forms.gle/tVGPhjKXyEsSgUcs8)!
+
+## Table of Contents
+
+- [Organization](#organization)
+- [Important dates](#important-dates)
+- [Communication](#communication)
+- [Projects](#projects)
+ - [How to propose](#how-to-propose-a-project)
+ - [How to form a team](#how-to-form-a-team-around-a-project)
+- [Tips & Tricks for project](#tips-on-how-to-organize-the-project)
+- [How to install flax, jax, optax, transformers, datasets](#how-to-install-relevant-libraries)
+- [Quickstart Flax/JAX](#quickstart-flax-and-jax)
+- [Quickstart Flax/JAX in 🤗 Transformers](#quickstart-flax-and-jax-in-transformers)
+ - [Flax design philosophy in 🤗 Transformers](#flax-design-philosophy-in-transformers)
+ - [How to use flax models & scripts](#how-to-use-flax-models-and-example-scripts)
+- [Talks](#talks)
+- [How to use the 🤗 Hub for training](#how-to-use-the-hub-for-collaboration)
+- [How to setup TPU VM](#how-to-setup-tpu-vm)
+- [How to build a demo](#how-to-build-a-demo)
+ - [Using the Hugging Face Widgets](#using-the-hugging-face-widgets)
+ - [Using a Streamlit demo](#using-a-streamlit-demo)
+ - [Using a Gradio demo](#using-a-gradio-demo)
+- [Project evaluation](#project-evaluation)
+- [General Tips & Tricks](#general-tips-and-tricks)
+- [FAQ](#faq)
+
+## Organization
+
+Participants can propose ideas for an interesting NLP and/or CV project. Teams of 3 to 5 will then be formed around the most promising and interesting projects. Make sure to read through the [Projects](#projects) section on how to propose projects, comment on other participants' project ideas, and create a team.
+
+To help each team successfully finish their project, we have organized talks by leading scientists and engineers from Google, Hugging Face, and the open-source NLP & CV community. The talks will take place before the community week from June 30th to July 2nd. Make sure to attend the talks to get the most out of your participation! Check out the [Talks](#talks) section to get an overview of the talks, including the speaker and the time of the talk.
+
+Each team is then given **free access to a TPUv3-8 VM** from July 7th to July 14th. In addition, we will provide training examples in JAX/Flax for a variety of NLP and Vision models to kick-start your project. During the week, we'll make sure to answer any questions you might have about JAX/Flax and Transformers and help each team as much as possible to complete their project!
+
+At the end of the community week, each team should submit a demo of their project. All demonstrations will be evaluated by a jury and the top-3 demos will be awarded a prize. Check out the [How to submit a demo](#how-to-submit-a-demo) section for more information and suggestions on how to submit your project.
+
+## Important dates
+
+- **23.06.** Official announcement of the community week. Make sure to sign-up in [this google form](https://forms.gle/tVGPhjKXyEsSgUcs8).
+- **23.06. - 30.06.** Participants will be added to an internal Slack channel. Project ideas can be proposed here and groups of 3-5 are formed. Read this document for more information.
+- **30.06.** Release of all relevant training scripts in JAX/Flax as well as other documents on how to set up a TPU, how to use the training scripts, how to submit a demo, tips & tricks for JAX/Flax, tips & tricks for efficient use of the hub.
+- **30.06. - 2.07.** Talks about JAX/Flax, TPU, Transformers, Computer Vision & NLP will be held.
+- **7.07.** Start of the community week! Access to TPUv3-8 will be given to each team.
+- **7.07. - 14.07.** The Hugging Face & JAX/Flax & Cloud team will be available for any questions, problems the teams might run into.
+- **15.07.** Access to TPU is deactivated and community week officially ends.
+- **16.07.** Deadline for each team to submit a demo.
+
+## Communication
+
+All important communication will take place in an internal Slack channel, called `#flax-jax-community-week`.
+Important announcements of the Hugging Face, Flax/JAX, and Google Cloud team will be posted there.
+Such announcements include general information about the community week (Dates, Rules, ...), release of relevant training scripts (Flax/JAX example scripts for NLP and Vision), release of other important documents (How to access the TPU), etc.
+The Slack channel will also be the central place for participants to post about their results, share their learning experiences, ask questions, etc.
+
+For issues with Flax/JAX, Transformers, Datasets or for questions that are specific to your project we would be **very happy** if you could use the following public repositories and forums:
+
+- Flax: [Issues](https://github.com/google/flax/issues), [Questions](https://github.com/google/flax/discussions)
+- JAX: [Issues](https://github.com/google/jax/issues), [Questions](https://github.com/google/jax/discussions)
+- 🤗 Transformers: [Issues](https://github.com/huggingface/transformers/issues), [Questions](https://discuss.huggingface.co/c/transformers/9)
+- 🤗 Datasets: [Issues](https://github.com/huggingface/datasets/issues), [Questions](https://discuss.huggingface.co/c/datasets/10)
+- Project specific questions: [Forum](https://discuss.huggingface.co/c/flax-jax-projects/22)
+- TPU related questions: [TODO]()
+
+Please do **not** post the complete issue/project-specific question in the Slack channel, but instead a link to your issue/question that we will try to answer as soon as possible.
+This way, we make sure that the everybody in the community can benefit from your questions - even after the community week - and that the same question is not answered twice.
+
+To be invited to the Slack channel, please make sure you have signed up [on the Google form](https://forms.gle/tVGPhjKXyEsSgUcs8).
+
+**Note**: If you have signed up on the google form, but you are not in the Slack channel, please leave a message on [(TODO) the official forum announcement]( ) and ping `@Suzana` and `@patrickvonplaten`.
+
+## Projects
+
+During the first week after the community week announcement, **23.06. - 30.06.**, teams will be formed around the most promising and interesting project ideas. Each team can consist of 2 to 10 participants. Projects can be accessed [here](https://discuss.huggingface.co/c/flax-jax-projects/22).
+
+All officially defined projects can be seen [here](https://docs.google.com/spreadsheets/d/1GpHebL7qrwJOc9olTpIPgjf8vOS0jNb6zR_B8x_Jtik/edit?usp=sharing).
+
+### How to propose a project
+
+Some default project ideas are given by the organizers. **However, we strongly encourage participants to submit their own project ideas!**
+Check out the [HOW_TO_PROPOSE_PROJECT.md](https://github.com/huggingface/transformers/tree/main/examples/research_projects/jax-projects/HOW_TO_PROPOSE_PROJECT.md) for more information on how to propose a new project.
+
+### How to form a team around a project
+
+You can check out all existing projects ideas on the forum under [Flax/JAX projects category](https://discuss.huggingface.co/c/flax-jax-projects/22).
+Make sure to quickly check out each project idea and leave a ❤️ if you like an idea.
+Feel free to leave comments, suggestions for improvement, or questions about more details directly on the discussion thread.
+If you have found the project that you ❤️ the most, leave a message "I would like to join this project" on the discussion thread.
+We strongly advise you to also shortly state who you are, which time zone you are in and why you would like to work on this project, how you can contribute to the project and what your vision is for the project.
+For projects that see a lot of interest and for which enough participants have expressed interest in joining, an official team will be created by the organizers.
+One of the organizers (`@Suzana`, `@valhalla`, `@osanseviero`, `@patrickvonplaten`) will leave a message "For this project the team: ``, `` , is officially created" on the thread and note down the teams on [this google sheet](https://docs.google.com/spreadsheets/d/1GpHebL7qrwJOc9olTpIPgjf8vOS0jNb6zR_B8x_Jtik/edit?usp=sharing).
+
+Once created, the team can start refining their project:
+
+- What is the goal of the project? *E.g.*, Present a language model that writes poetry in Russian.
+- What model will we use? *E.g.*, FlaxGPT2
+- What data will we use? *E.g.* Russian dataset of OSCAR & publicly available book on poetry
+- Should we use a pre-trained model or train a model from scratch? E.g. Train a model from scratch
+- What training scripts do we need? *E.g.* `transformers/examples/flax/run_clm_flax.py` can be used
+- What kind of demo would we like to present? E.g. Text-generation API of the 🤗 Hub in combination with a Streamlit demo that lets the user generate a poem of a given length
+- How will the work be divided? *E.g.* Team member 1 works on data preprocessing, Team member 2 works on adapting the Flax script, ...
+
+We highly recommend that each team discusses all relevant ideas for their project directly on the forum thread.
+This way valuable learning experiences are shared and accessible by the whole community in the future.
+Additionally, the organizers, other participants, or anybody in the community really can read through your discussions and leave comments/tips for improvement. Obviously, you can also create private chats, ... to discuss more sensitive topics, etc.
+
+**Important**:
+
+- For project ideas that see a lot of interest, we are more than happy to create more than one team.
+- Participants are welcome to join multiple teams, even though we encourage them to only work on a single project.
+- Under special circumstances, participants can change/create new teams. Please note that we would like to keep this the exception. If however, you would like to change/leave existing teams, please leave a post on the project's thread where you ping the corresponding organizer that created the group.
+ - It is often easy to propose/join a project that is done in your native language. Feel free to reach out to existing [language-specific groups](https://discuss.huggingface.co/c/languages-at-hugging-face/15) to look for community members that might be interested in joining your project.
+
+## Tips on how to organize the project
+
+This section gives you some tips on how to most efficiently & effectively
+work as a team to achieve your goal. It is by no means a strict recipe to follow,
+but rather a collection of tips from the 🤗 team.
+
+Once your team is defined, you can start working on the project as soon as possible.
+
+
+### Communication
+
+At first, it is always useful to get to know each other and to set up a means of communication.
+While we recommend that all technical aspects of work can be discussed directly on the [forum](https://discuss.huggingface.co/c/flax-jax-projects/22) under your project thread,
+it can be very helpful to have a more direct way of communicating, *e.g.* in a channel.
+For this we have created a discord that you can access [here](https://discord.com/channels/858019234139602994/858019234139602997).
+This discord will not be managed by anybody and is just there so that you can communicate more effectively with your team members.
+Feel free to create a new channel for you and your team where you can discuss everything. If you and your team have already set up other ways of communicating, it is absolutely not required to make use of the discord. However, we do recommend each team to set up some kind
+of channel or group for quick discussions.
+
+### Project definition
+
+In the very beginning, you should make sure your project is well-defined and that
+everybody in the team understands the goal of the project and the work that needs to be
+done in order to achieve the goal. A well-defined project:
+
+- has defined the task on which the model will be trained
+- has defined the model that will be trained
+- has defined the datasets that will be used for training
+- has defined the type of training scripts that need to be written
+- has defined the desired outcome of the project
+- has defined the workflows
+
+By "has defined" we don't meant that the corresponding code already has to be written and ready
+to be used, but that everybody in team is on the same page on what type of model, data and training script should be used.
+
+To give an example, a well-defined project would be the following:
+
+- task: summarization
+- model: [google-t5/t5-small](https://huggingface.co/google-t5/t5-small)
+- dataset: [CNN/Daily mail](https://huggingface.co/datasets/cnn_dailymail)
+- training script: [run_summarization_flax.py](https://github.com/huggingface/transformers/blob/main/examples/flax/summarization/run_summarization_flax.py)
+- outcome: t5 model that can summarize news
+- work flow: adapt `run_summarization_flax.py` to work with `google-t5/t5-small`.
+
+This example is a very easy and not the most interesting project since a `google-t5/t5-small`
+summarization model exists already for CNN/Daily mail and pretty much no code has to be
+written.
+A well-defined project does not need to have the dataset be part of
+the `datasets` library and the training script already be pre-written, however it should
+be clear how the desired dataset can be accessed and how the training script can be
+written.
+
+It is also important to have a clear plan regarding the workflow. Usually, the
+data processing is done in a first step. Once the data is in a format that the model can
+work with, the training script can be written, etc. These steps should be more detailed
+once the team has a clearly defined project. It can be helpful to set deadlines for each step.
+
+### Workload division
+
+To effectively work as a team, it is crucial to divide the workload among everybody.
+Some team members will be more motivated and experienced than others and
+some team members simply want to participate to learn more and cannot contribute that
+much to the team. This is totally fine! One cannot expect everybody in the team to have the same level of experience and time/motivation during the community week.
+
+As a conclusion, being honest about one's expected involvement is crucial so that
+the workload can be divided accordingly. If someone doesn't think her/his tasks are feasible - let
+the team know early on so that someone else can take care of it!
+
+It is recommended that the motivated and experienced team members take the lead in dividing the work and are ready to take over the tasks of another team member if necessary.
+
+The workload can often be divided according to:
+
+- data preprocessing (load the data and preprocess data in the correct format)
+- data tokenization / data collator (process data samples into tokens or images)
+- model configuration (writing the code that defines the model)
+- model forward pass (make sure input / output work correctly)
+- loss function (define the loss function)
+- putting the pieces together in a training script
+
+Many of the steps above require other steps to be finished, so it often makes sense
+to use dummy data in the expected format to start, *e.g.*, with the model forward pass
+before the data preprocessing is done.
+
+### Expectations
+
+It is also very important to stay realistic with the scope of your project. Each team
+has access to a TPUv3-8 for only *ca.* 10 days, so it's important to keep the scope of
+the project reasonable. While we do want each team to work on interesting projects, each
+team should make sure that the project goals can be achieved within the provided compute
+time on TPU. For instance, pretraining a 11 billion parameters T5 model is not really a realistic
+task with just 10 days of TPUv3-8 compute.
+Also, it might be difficult to finish a project where the whole modeling, dataset and training code has to be written from scratch.
+
+Having defined your project, feel free to reach out on Slack or the forum for feedback from the organizers. We can surely give you our opinion on whether the project is feasible and what can be done to improve it.
+the project is feasible.
+
+### Other tips
+
+Here is a collection of some more tips:
+
+- We strongly recommend to work as publicly and collaboratively as possible during the week so that other teams
+and the organizers can best help you. This includes publishing important discussions on
+the forum and making use of the [🤗 hub](http://huggingface.co/) to have a version
+control for your models and training logs.
+- When debugging, it is important that the debugging cycle is kept as short as possible to
+be able to effectively debug. *E.g.* if there is a problem with your training script,
+you should run it with just a couple of hundreds of examples and not the whole dataset script. This can be done by either making use of [datasets streaming](https://huggingface.co/docs/datasets/master/dataset_streaming?highlight=streaming) or by selecting just the first
+X number of data samples after loading:
+
+```python
+datasets["train"] = datasets["train"].select(range(1000))
+```
+- Ask for help. If you are stuck, use the public Slack channel or the [forum](https://discuss.huggingface.co/c/flax-jax-projects/22) to ask for help.
+
+## How to install relevant libraries
+
+In the following we will explain how to install all relevant libraries on your local computer and on TPU VM.
+
+It is recommended to install all relevant libraries both on your local machine
+and on the TPU virtual machine. This way, quick prototyping and testing can be done on
+your local machine and the actual training can be done on the TPU VM.
+
+### Local computer
+
+The following libraries are required to train a JAX/Flax model with 🤗 Transformers and 🤗 Datasets:
+
+- [JAX](https://github.com/google/jax/)
+- [Flax](https://github.com/google/flax)
+- [Optax](https://github.com/deepmind/optax)
+- [Transformers](https://github.com/huggingface/transformers)
+- [Datasets](https://github.com/huggingface/datasets)
+
+You should install the above libraries in a [virtual environment](https://docs.python.org/3/library/venv.html).
+If you're unfamiliar with Python virtual environments, check out the [user guide](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/). Create a virtual environment with the version of Python you're going
+to use and activate it.
+
+You should be able to run the command:
+
+```bash
+python3 -m venv
+```
+
+You can activate your venv by running
+
+```bash
+source ~//bin/activate
+```
+
+We strongly recommend to make use of the provided JAX/Flax examples scripts in [transformers/examples/flax](https://github.com/huggingface/transformers/tree/main/examples/flax) even if you want to train a JAX/Flax model of another github repository that is not integrated into 🤗 Transformers.
+In all likelihood, you will need to adapt one of the example scripts, so we recommend forking and cloning the 🤗 Transformers repository as follows.
+Doing so will allow you to share your fork of the Transformers library with your team members so that the team effectively works on the same code base. It will also automatically install the newest versions of `flax`, `jax` and `optax`.
+
+1. Fork the [repository](https://github.com/huggingface/transformers) by
+ clicking on the 'Fork' button on the repository's page. This creates a copy of the code
+ under your GitHub user account.
+
+2. Clone your fork to your local disk, and add the base repository as a remote:
+
+ ```bash
+ $ git clone https://github.com//transformers.git
+ $ cd transformers
+ $ git remote add upstream https://github.com/huggingface/transformers.git
+ ```
+
+3. Create a new branch to hold your development changes. This is especially useful to share code changes with your team:
+
+ ```bash
+ $ git checkout -b a-descriptive-name-for-my-project
+ ```
+
+4. Set up a flax environment by running the following command in a virtual environment:
+
+ ```bash
+ $ pip install -e ".[flax]"
+ ```
+
+ (If transformers was already installed in the virtual environment, remove
+ it with `pip uninstall transformers` before reinstalling it in editable
+ mode with the `-e` flag.)
+
+ If you have already cloned that repo, you might need to `git pull` to get the most recent changes in the `datasets`
+ library.
+
+ Running this command will automatically install `flax`, `jax` and `optax`.
+
+Next, you should also install the 🤗 Datasets library. We strongly recommend installing the
+library from source to profit from the most current additions during the community week.
+
+Simply run the following steps:
+
+```bash
+$ cd ~/
+$ git clone https://github.com/huggingface/datasets.git
+$ cd datasets
+$ pip install -e ".[streaming]"
+```
+
+If you plan on contributing a specific dataset during
+the community week, please fork the datasets repository and follow the instructions
+[here](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-create-a-pull-request).
+
+To verify that all libraries are correctly installed, you can run the following command.
+It assumes that both `transformers` and `datasets` were installed from main - otherwise
+datasets streaming will not work correctly.
+
+```python
+from transformers import FlaxRobertaModel, RobertaTokenizerFast
+from datasets import load_dataset
+import jax
+
+dataset = load_dataset('oscar', "unshuffled_deduplicated_en", split='train', streaming=True)
+
+dummy_input = next(iter(dataset))["text"]
+
+tokenizer = RobertaTokenizerFast.from_pretrained("FacebookAI/roberta-base")
+input_ids = tokenizer(dummy_input, return_tensors="np").input_ids[:, :10]
+
+model = FlaxRobertaModel.from_pretrained("julien-c/dummy-unknown")
+
+# run a forward pass, should return an object `FlaxBaseModelOutputWithPooling`
+model(input_ids)
+```
+
+### TPU VM
+
+**VERY IMPORTANT** - Only one process can access the TPU cores at a time. This means that if multiple team members
+are trying to connect to the TPU cores errors, such as:
+
+```
+libtpu.so already in used by another process. Not attempting to load libtpu.so in this process.
+```
+
+are thrown. As a conclusion, we recommend every team member to create her/his own virtual environment, but only one
+person should run the heavy training processes. Also, please take turns when setting up the TPUv3-8 so that everybody
+can verify that JAX is correctly installed.
+
+The following libraries are required to train a JAX/Flax model with 🤗 Transformers and 🤗 Datasets on TPU VM:
+
+- [JAX](https://github.com/google/jax/)
+- [Flax](https://github.com/google/flax)
+- [Optax](https://github.com/deepmind/optax)
+- [Transformers](https://github.com/huggingface/transformers)
+- [Datasets](https://github.com/huggingface/datasets)
+
+You should install the above libraries in a [virtual environment](https://docs.python.org/3/library/venv.html).
+If you're unfamiliar with Python virtual environments, check out the [user guide](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/). Create a virtual environment with the version of Python you're going
+to use and activate it.
+
+You should be able to run the command:
+
+```bash
+python3 -m venv
+```
+
+If this doesn't work, you first might to have install `python3-venv`. You can do this as follows:
+
+```bash
+sudo apt-get install python3-venv
+```
+
+You can activate your venv by running
+
+```bash
+source ~//bin/activate
+```
+
+Next you should install JAX's TPU version on TPU by running the following command:
+
+```bash
+$ pip install requests
+```
+
+and then:
+
+```bash
+$ pip install "jax[tpu]>=0.2.16" -f https://storage.googleapis.com/jax-releases/libtpu_releases.html
+```
+
+**Note**: Running this command might actually throw an error, such as:
+```
+ Building wheel for jax (setup.py) ... error
+ ERROR: Command errored out with exit status 1:
+ command: /home/patrick/patrick/bin/python3 -u -c 'import sys, setuptools, tokenize; sys.argv[0] = '"'"'/tmp/pip-install-lwseckn1/jax/setup.py'"'"'; __file__='"'"'/tmp/pip-install-lwseckn1/jax/setup.py'"'"';f=getattr(tokenize, '"'"'open'"'"', open)(__file__);code=f.read().replace('"'"'\r\n'"'"', '"'"'\n'"'"');f.close();exec(compile(code, __file__, '"'"'exec'"'"'))' bdist_wheel -d /tmp/pip-wheel-pydotzlo
+ cwd: /tmp/pip-install-lwseckn1/jax/
+ Complete output (6 lines):
+ usage: setup.py [global_opts] cmd1 [cmd1_opts] [cmd2 [cmd2_opts] ...]
+ or: setup.py --help [cmd1 cmd2 ...]
+ or: setup.py --help-commands
+ or: setup.py cmd --help
+
+ error: invalid command 'bdist_wheel'
+ ----------------------------------------
+ ERROR: Failed building wheel for jax
+```
+Jax should have been installed correctly nevertheless.
+
+To verify that JAX was correctly installed, you can run the following command:
+
+```python
+import jax
+jax.device_count()
+```
+
+This should display the number of TPU cores, which should be 8 on a TPUv3-8 VM.
+
+We strongly recommend to make use of the provided JAX/Flax examples scripts in [transformers/examples/flax](https://github.com/huggingface/transformers/tree/main/examples/flax) even if you want to train a JAX/Flax model of another github repository that is not integrated into 🤗 Transformers.
+In all likelihood, you will need to adapt one of the example scripts, so we recommend forking and cloning the 🤗 Transformers repository as follows.
+Doing so will allow you to share your fork of the Transformers library with your team members so that the team effectively works on the same code base. It will also automatically install the newest versions of `flax`, `jax` and `optax`.
+
+1. Fork the [repository](https://github.com/huggingface/transformers) by
+ clicking on the 'Fork' button on the repository's page. This creates a copy of the code
+ under your GitHub user account.
+
+2. Clone your fork to your local disk, and add the base repository as a remote:
+
+ ```bash
+ $ git clone https://github.com//transformers.git
+ $ cd transformers
+ $ git remote add upstream https://github.com/huggingface/transformers.git
+ ```
+
+3. Create a new branch to hold your development changes. This is especially useful to share code changes with your team:
+
+ ```bash
+ $ git checkout -b a-descriptive-name-for-my-project
+ ```
+
+4. Set up a flax environment by running the following command in a virtual environment:
+
+ ```bash
+ $ pip install -e ".[flax]"
+ ```
+
+ (If transformers was already installed in the virtual environment, remove
+ it with `pip uninstall transformers` before reinstalling it in editable
+ mode with the `-e` flag.)
+
+ If you have already cloned that repo, you might need to `git pull` to get the most recent changes in the `datasets`
+ library.
+
+ Running this command will automatically install `flax`, `jax` and `optax`.
+
+Next, you should also install the 🤗 Datasets library. We strongly recommend installing the
+library from source to profit from the most current additions during the community week.
+
+Simply run the following steps:
+
+```bash
+$ cd ~/
+$ git clone https://github.com/huggingface/datasets.git
+$ cd datasets
+$ pip install -e ".[streaming]"
+```
+
+If you plan on contributing a specific dataset during
+the community week, please fork the datasets repository and follow the instructions
+[here](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-create-a-pull-request).
+
+To verify that all libraries are correctly installed, you can run the following command.
+It assumes that both `transformers` and `datasets` were installed from main - otherwise
+datasets streaming will not work correctly.
+
+```python
+from transformers import FlaxRobertaModel, RobertaTokenizerFast
+from datasets import load_dataset
+import jax
+
+dataset = load_dataset('oscar', "unshuffled_deduplicated_en", split='train', streaming=True)
+
+dummy_input = next(iter(dataset))["text"]
+
+tokenizer = RobertaTokenizerFast.from_pretrained("FacebookAI/roberta-base")
+input_ids = tokenizer(dummy_input, return_tensors="np").input_ids[:, :10]
+
+model = FlaxRobertaModel.from_pretrained("julien-c/dummy-unknown")
+
+# run a forward pass, should return an object `FlaxBaseModelOutputWithPooling`
+model(input_ids)
+```
+
+## Quickstart flax and jax
+
+[JAX](https://jax.readthedocs.io/en/latest/index.html) is Autograd and XLA, brought together for high-performance numerical computing and machine learning research. It provides composable transformations of Python+NumPy programs: differentiate, vectorize, parallelize, Just-In-Time compile to GPU/TPU, and more. A great place for getting started with JAX is the [JAX 101 Tutorial](https://jax.readthedocs.io/en/latest/jax-101/index.html).
+
+[Flax](https://flax.readthedocs.io/en/latest/index.html) is a high-performance neural network library designed for flexibility built on top of JAX. It aims to provide users with full control of their training code and is carefully designed to work well with JAX transformations such as `grad` and `pmap` (see the [Flax philosophy](https://flax.readthedocs.io/en/latest/philosophy.html)). For an introduction to Flax see the [Flax Basics Colab](https://flax.readthedocs.io/en/latest/notebooks/flax_basics.html) or the list of curated [Flax examples](https://flax.readthedocs.io/en/latest/examples.html).
+
+## Quickstart flax and jax in transformers
+
+Currently, we support the following models in Flax.
+Note that some models are about to be merged to `main` and will
+be available in a couple of days.
+
+- [BART](https://github.com/huggingface/transformers/blob/main/src/transformers/models/bart/modeling_flax_bart.py)
+- [BERT](https://github.com/huggingface/transformers/blob/main/src/transformers/models/bert/modeling_flax_bert.py)
+- [BigBird](https://github.com/huggingface/transformers/blob/main/src/transformers/models/big_bird/modeling_flax_big_bird.py)
+- [CLIP](https://github.com/huggingface/transformers/blob/main/src/transformers/models/clip/modeling_flax_clip.py)
+- [ELECTRA](https://github.com/huggingface/transformers/blob/main/src/transformers/models/electra/modeling_flax_electra.py)
+- [GPT2](https://github.com/huggingface/transformers/blob/main/src/transformers/models/openai-community/gpt2/modeling_flax_gpt2.py)
+- [(TODO) MBART](https://github.com/huggingface/transformers/blob/main/src/transformers/models/mbart/modeling_flax_mbart.py)
+- [RoBERTa](https://github.com/huggingface/transformers/blob/main/src/transformers/models/roberta/modeling_flax_roberta.py)
+- [T5](https://github.com/huggingface/transformers/blob/main/src/transformers/models/t5/modeling_flax_t5.py)
+- [ViT](https://github.com/huggingface/transformers/blob/main/src/transformers/models/vit/modeling_flax_vit.py)
+- [Wav2Vec2](https://github.com/huggingface/transformers/blob/main/src/transformers/models/wav2vec2/modeling_flax_wav2vec2.py)
+
+You can find all available training scripts for JAX/Flax under the
+official [flax example folder](https://github.com/huggingface/transformers/tree/main/examples/flax). Note that a couple of training scripts will be released in the following week.
+
+- [Causal language modeling (GPT2)](https://github.com/huggingface/transformers/blob/main/examples/flax/language-modeling/run_clm_flax.py)
+- [Masked language modeling (BERT, RoBERTa, ELECTRA, BigBird)](https://github.com/huggingface/transformers/blob/main/examples/flax/language-modeling/run_mlm_flax.py)
+- [Text classification (BERT, RoBERTa, ELECTRA, BigBird)](https://github.com/huggingface/transformers/blob/main/examples/flax/text-classification/run_flax_glue.py)
+- [Summarization / Seq2Seq (BART, MBART, T5)](https://github.com/huggingface/transformers/blob/main/examples/flax/summarization/run_summarization_flax.py)
+- [Masked Seq2Seq pret-training (T5)](https://github.com/huggingface/transformers/blob/main/examples/flax/language-modeling/run_t5_mlm_flax.py)
+- [Contrastive Loss pretraining for Wav2Vec2](https://github.com/huggingface/transformers/blob/main/examples/research_projects/jax-projects/wav2vec2)
+- [Fine-tuning long-range QA for BigBird](https://github.com/huggingface/transformers/blob/main/examples/research_projects/jax-projects/big_bird)
+- [(TODO) Image classification (ViT)]( )
+- [(TODO) CLIP pretraining, fine-tuning (CLIP)]( )
+
+
+### **Flax design philosophy in Transformers**
+
+This section will explain how Flax models are implemented in Transformers and how the design differs from PyTorch.
+
+Let's first go over the difference between Flax and PyTorch.
+
+In JAX, most transformations (notably `jax.jit`) require functions that are transformed to be stateless so that they have no side effects. This is because any such side-effects will only be executed once when the transformed function is run during compilation and all subsequent calls of the compiled function would re-use the same side-effects of the compiled run instead of the "actual" side-effects (see [Stateful Computations in JAX](https://jax.readthedocs.io/en/latest/jax-101/07-state.html)). As a consequence, Flax models, which are designed to work well with JAX transformations, are stateless. This means that when running a model in inference, both the inputs and the model weights are passed to the forward pass. In contrast, PyTorch model are very much stateful with the weights being stored within the model instance and the user just passing the inputs to the forward pass.
+
+Let's illustrate the difference between stateful models in PyTorch and stateless models in Flax.
+
+For simplicity, let's assume the language model consists simply of a single attention layer [`key_proj`, `value_proj`, `query_proj`] and a linear layer `logits_proj` to project the transformed word embeddings to the output logit vectors.
+
+#### **Stateful models in PyTorch**
+
+In PyTorch, the weights matrices would be stored as `torch.nn.Linear` objects alongside the model's config inside the model class `ModelPyTorch`:
+
+```python
+class ModelPyTorch:
+
+ def __init__(self, config):
+ self.config = config
+ self.key_proj = torch.nn.Linear(config)
+ self.value_proj = torch.nn.Linear(config)
+ self.query_proj = torch.nn.Linear(config)
+ self.logits_proj = torch.nn.Linear(config)
+```
+
+Instantiating an object `model_pytorch` of the class `ModelPyTorch` would actually allocate memory for the model weights and attach them to the attributes `self.key_proj`, `self.value_proj`, `self.query_proj`, and `self.logits.proj`. We could access the weights via:
+
+```python
+key_projection_matrix = model_pytorch.key_proj.weight.data
+```
+
+Visually, we would represent an object of `model_pytorch` therefore as follows:
+
+
+
+Executing a forward pass then simply corresponds to passing the `input_ids` to the object `model_pytorch`:
+
+```python
+sequences = model_pytorch(input_ids)
+```
+
+In a more abstract way, this can be represented as passing the word embeddings to the model function to get the output logits:
+
+
+
+This design is called **stateful** because the output logits, the `sequences`, can change even if the word embeddings, the `input_ids`, stay the same. Hence, the function's output does not only depend on its inputs, but also on its **state**, `[self.key_proj, self.value_proj, self.query_proj, self.logits_proj]`, which makes `model_pytorch` stateful.
+
+#### **Stateless models in Flax/JAX**
+
+Now, let's see how the mathematically equivalent model would be written in JAX/Flax. The model class `ModelFlax` would define the self-attention and logits projection weights as [**`flax.linen.Dense`**](https://flax.readthedocs.io/en/latest/_autosummary/flax.linen.Dense.html#flax.linen.Dense) objects:
+
+```python
+class ModelFlax:
+
+ def __init__(self, config):
+ self.config = config
+ self.key_proj = flax.linen.Dense(config)
+ self.value_proj = flax.linen.Dense(config)
+ self.query_proj = flax.linen.Dense(config)
+ self.logits_proj = flax.linen.Dense(config)
+```
+
+At first glance the linear layer class `flax.linen.Dense` looks very similar to PyTorch's `torch.nn.Linear` class. However, instantiating an object `model_flax` only defines the linear transformation functions and does **not** allocate memory to store the linear transformation weights. In a way, the attribute `self.key_proj` tell the instantiated object `model_flax` to perform a linear transformation on some input and force it to expect a weight, called `key_proj`, as an input.
+
+This time we would illustrate the object `model_flax` without the weight matrices:
+
+
+
+
+Accordingly, the forward pass requires both `input_ids` as well as a dictionary consisting of the model's weights (called `state` here) to compute the `sequences`:
+
+To get the initial `state` we need to explicitly do a forward pass by passing a dummy input:
+
+```python
+state = model_flax.init(rng, dummy_input_ids)
+```
+
+and then we can do the forward pass.
+
+```python
+sequences = model_flax.apply(state, input_ids)
+```
+
+Visually, the forward pass would now be represented as passing all tensors required for the computation to the model's object:
+
+
+
+This design is called **stateless** because the output logits, the `sequences`, **cannot** change if the word embeddings, the `input_ids`, stay the same. Hence, the function's output only depends on its inputs, being the `input_ids` and the `state` dictionary consisting of the weights **state**, `[key_proj, value_proj, query_proj, logits_proj]`.
+
+Another term which is often used to describe the design difference between Flax/JAX and PyTorch is **immutable** vs **mutable**. A instantiated Flax model, `model_flax`, is **immutable** as a logical consequence of `model_flax`'s output being fully defined by its input: If calling `model_flax` could mutate `model_flax`, then calling `model_flax` twice with the same inputs could lead to different results which would violate the "*statelessness*" of Flax models.
+
+#### **Flax models in Transformers**
+
+Now let us see how this is handled in `Transformers.` If you have used a Flax model in Transformers already, you might wonder how come you don't always have to pass the parameters to the function of the forward pass. This is because the `FlaxPreTrainedModel` class abstracts it away.
+It is designed this way so that the Flax models in Transformers will have a similar API to PyTorch and Tensorflow models.
+
+The `FlaxPreTrainedModel` is an abstract class that holds a Flax module, handles weights initialization, and provides a simple interface for downloading and loading pre-trained weights i.e. the `save_pretrained` and `from_pretrained` methods. Each Flax model then defines its own subclass of `FlaxPreTrainedModel`; *e.g.* the BERT model has `FlaxBertPreTrainedModel`. Each such class provides two important methods, `init_weights` and `__call__`. Let's see what each of those methods do:
+
+- The `init_weights` method takes the expected input shape and a [`PRNGKey`](https://jax.readthedocs.io/en/latest/_autosummary/jax.random.PRNGKey.html) (and any other arguments that are required to get initial weights) and calls `module.init` by passing it a random example to get the initial weights with the given `dtype` (for ex. `fp32` or `bf16` etc). This method is called when we create an instance of the model class, so the weights are already initialized when you create a model i.e., when you do
+
+ model = FlaxBertModel(config)
+
+- The `__call__` method defines forward pass. It takes all necessary model inputs and parameters (and any other arguments required for the forward pass). The parameters are optional; when no parameters are passed, it uses the previously initialized or loaded parameters which can be accessed using `model.params`. It then calls the `module.apply` method, passing it the parameters and inputs to do the actual forward pass. So we can do a forward pass using
+
+ output = model(inputs, params=params)
+
+
+Let's look at an example to see how this works. We will write a simple two-layer MLP model.
+
+First, write a Flax module that will declare the layers and computation.
+
+```python
+import flax.linen as nn
+import jax.numpy as jnp
+
+class MLPModule(nn.Module):
+ config: MLPConfig
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.dense1 = nn.Dense(self.config.hidden_dim, dtype=self.dtype)
+ self.dense2 = nn.Desne(self.config.hidden_dim, dtype=self.dtype)
+
+ def __call__(self, inputs):
+ hidden_states = self.dense1(inputs)
+ hidden_states = nn.relu(hidden_states)
+ hidden_states = self.dense2(hidden_states)
+ return hidden_states
+```
+
+Now let's define the `FlaxPreTrainedModel` model class.
+
+```python
+from transformers.modeling_flax_utils import FlaxPreTrainedModel
+
+class FlaxMLPPreTrainedModel(FlaxPreTrainedModel):
+ config_class = MLPConfig
+ base_model_prefix = "model"
+ module_class: nn.Module = None
+
+ def __init__(self, config: BertConfig, input_shape: Tuple = (1, 8), seed: int = 0, dtype: jnp.dtype = jnp.float32, **kwargs):
+ # initialize the flax module
+ module = self.module_class(config=config, dtype=dtype, **kwargs)
+ super().__init__(config, module, input_shape=input_shape, seed=seed, dtype=dtype)
+
+ def init_weights(self, rng, input_shape):
+ # init input tensors
+ inputs = jnp.zeros(input_shape, dtype="i4")
+
+ params_rng, dropout_rng = jax.random.split(rng)
+ rngs = {"params": params_rng, "dropout": dropout_rng}
+
+ params = self.module.init(rngs, inputs)["params"]
+ return params
+
+ def __call__(self, inputs, params: dict = None):
+ params = {"params": params or self.params}
+ outputs = self.module.apply(params, jnp.array(inputs))
+ return outputs
+```
+
+
+Now we can define our model class as follows.
+
+```python
+class FlaxMLPModel(FlaxMLPPreTrainedModel):
+ module_class = FlaxMLPModule
+```
+
+Now the `FlaxMLPModel` will have a similar interface as PyTorch or Tensorflow models and allows us to attach loaded or randomly initialized weights to the model instance.
+
+So the important point to remember is that the `model` is not an instance of `nn.Module`; it's an abstract class, like a container that holds a Flax module, its parameters and provides convenient methods for initialization and forward pass. The key take-away here is that an instance of `FlaxMLPModel` is very much stateful now since it holds all the model parameters, whereas the underlying Flax module `FlaxMLPModule` is still stateless. Now to make `FlaxMLPModel` fully compliant with JAX transformations, it is always possible to pass the parameters to `FlaxMLPModel` as well to make it stateless and easier to work with during training. Feel free to take a look at the code to see how exactly this is implemented for ex. [`modeling_flax_bert.py`](https://github.com/huggingface/transformers/blob/main/src/transformers/models/bert/modeling_flax_bert.py#L536)
+
+Another significant difference between Flax and PyTorch models is that, we can pass the `labels` directly to PyTorch's forward pass to compute the loss, whereas Flax models never accept `labels` as an input argument. In PyTorch, gradient backpropagation is performed by simply calling `.backward()` on the computed loss which makes it very handy for the user to be able to pass the `labels`. In Flax however, gradient backpropagation cannot be done by simply calling `.backward()` on the loss output, but the loss function itself has to be transformed by `jax.grad` or `jax.value_and_grad` to return the gradients of all parameters. This transformation cannot happen under-the-hood when one passes the `labels` to Flax's forward function, so that in Flax, we simply don't allow `labels` to be passed by design and force the user to implement the loss function oneself. As a conclusion, you will see that all training-related code is decoupled from the modeling code and always defined in the training scripts themselves.
+
+### **How to use flax models and example scripts**
+
+
+#### **How to do a forward pass**
+
+Let's first see how to load, save and do inference with Flax models. As explained in the above section, all Flax models in Transformers have similar API to PyTorch models, so we can use the familiar `from_pretrained` and `save_pretrained` methods to load and save Flax models.
+
+Let's use the base `FlaxRobertaModel` without any heads as an example.
+
+```python
+from transformers import FlaxRobertaModel, RobertaTokenizerFast
+import jax
+
+tokenizer = RobertaTokenizerFast.from_pretrained("FacebookAI/roberta-base")
+inputs = tokenizer("JAX/Flax is amazing ", padding="max_length", max_length=128, return_tensors="np")
+
+model = FlaxRobertaModel.from_pretrained("julien-c/dummy-unknown")
+
+@jax.jit
+def run_model(input_ids, attention_mask):
+ # run a forward pass, should return an object `FlaxBaseModelOutputWithPooling`
+ return model(input_ids, attention_mask)
+
+outputs = run_model(**inputs)
+```
+
+We use `jax.jit` to compile the function to get maximum performance. Note that in the above example, we set `padding=max_length` to pad all examples to the same length. We do this because JAX's compiler has to recompile a function everytime its input shape changes - in a sense a compiled function is not only defined by its code but also by its input and output shape. It is usually much more effective to pad the input to be of a fixed static shape than having to recompile every the function multiple times.
+
+
+#### **How to write a training loop**
+
+Now let's see how we can write a simple training loop to train Flax models, we will use `FlaxGPT2ForCausalLM` as an example.
+
+A training loop for Flax models typically consists of
+- A loss function that takes the parameters and inputs, runs the forward pass and returns the loss.
+- We then transform the loss function using `jax.grad` or `jax.value_and_grad` so that we get the gradients of all parameters.
+- An optimizer to update the paramteres using the gradients returned by the transformed loss function.
+- A train step function which combines the loss function and optimizer update, does the forward and backward pass and returns the updated parameters.
+
+Lets see how that looks like in code:
+
+First initialize our model
+
+```python
+import jax
+import jax.numpy as jnp
+
+from transformers import FlaxGPT2ForCausalLM
+
+model = FlaxGPT2ForCausalLM(config)
+```
+
+As explained above we don't compute the loss inside the model, but rather in the task-specific training script.
+For demonstration purposes, we write a pseudo training script for causal language modeling in the following.
+
+```python
+from flax.training.common_utils import onehot
+
+def cross_entropy(logits, labels):
+ return -jnp.sum(labels * jax.nn.log_softmax(logits, axis=-1), axis=-1)
+
+# define a function which will run the forward pass return loss
+def compute_loss(params, input_ids, labels):
+ logits = model(input_ids, params=params, train=True)
+ num_classes = logits.shape[-1]
+ loss = cross_entropy(logits, onehot(labels, num_classes)).mean()
+ return loss
+```
+
+Now we transform the loss function with `jax.value_and_grad`.
+
+```python
+# transform the loss function to get the gradients
+grad_fn = jax.value_and_grad(compute_loss)
+```
+
+We use the [optax](https://github.com/deepmind/optax) library to Initialize the optimizer.
+
+```python
+import optax
+
+params = model.params
+tx = optax.sgd(learning_rate=3e-3)
+opt_state = tx.init(params)
+```
+
+Now we define a single training step which will do a forward and a backward pass.
+
+```python
+def _train_step(params, opt_state, input_ids, labels)
+ # do the forward pass and get the loss and gradients
+ loss, grads = grad_fn(params, input_ids, labels)
+
+ # use the gradients to update parameters
+ updates, opt_state = tx.update(grads, opt_state)
+ updated_params = optax.apply_updates(params, updates)
+
+ return updates_params, opt_state, loss
+
+train_step = jax.jit(_train_step)
+```
+
+Finally, let's run our training loop.
+
+```python
+# train loop
+for i in range(10):
+ params, opt_state, loss = train_step(params, opt_state, input_ids, labels)
+```
+
+Note how we always pass the `params` and `opt_state` to the `train_step` which then returns the updated `params` and `opt_state`. This is because of the staless nature of JAX/Flax models, all the state
+like parameters, optimizer state is kept external.
+
+We can now save the model with the trained parameters using
+
+```python
+model.save_pretrained("awesome-flax-model", params=params)
+```
+
+Note that, as JAX is backed by the [XLA](https://www.tensorflow.org/xla) compiler any JAX/Flax code can run on all `XLA` compliant device without code change!
+That menas you could use the same training script on CPUs, GPUs, TPUs.
+
+To know more about how to train the Flax models on different devices (GPU, multi-GPUs, TPUs) and use the example scripts, please look at the [examples README](https://github.com/huggingface/transformers/tree/main/examples/flax).
+
+## Talks
+
+3 days of talks around JAX / Flax, Transformers, large-scale language modeling and other great topics during our community event!
+
+### Wednesday, June 30th
+- [Watch the talks on YouTube](https://www.youtube.com/watch?v=fuAyUQcVzTY)
+- [Chat history](https://docs.google.com/spreadsheets/d/1PZ5xYV2hVwlAVQSqDag65ympv5YNCSDmXyG-eWTaZ_o/edit?usp=sharing)
+
+ Speaker | Topic | Time | Video |
+|-------------|---------------------------------|------------------------|------------------------|
+| Skye Wanderman-Milne, Google Brain | Intro to JAX on Cloud TPUs | 6.00pm-6.45pm CEST / 9.00am-9.45am PST | [](https://www.youtube.com/watch?v=fuAyUQcVzTY) |
+| Marc van Zee, Google Brain | Introduction to Flax | 6.45pm-7.30pm CEST / 9.45am-10.30am PST | [](https://youtu.be/fuAyUQcVzTY?t=2569) |
+| Pablo Castro, Google Brain | Using Jax & Flax for RL with the Dopamine library | 7.30pm-8.00pm CEST / 10.30am-11.00am PST | [](https://youtu.be/fuAyUQcVzTY?t=5306) |
+
+### Thursday, July 1st
+- [Watch the talks on YouTube](https://www.youtube.com/watch?v=__eG63ZP_5g)
+- [Chat history](https://docs.google.com/spreadsheets/d/1PZ5xYV2hVwlAVQSqDag65ympv5YNCSDmXyG-eWTaZ_o/edit#gid=1515796400)
+
+ Speaker | Topic | Time | Video |
+|-------------|---------------------------------|------------------------|------------------------|
+| Suraj Patil & Patrick von Platen, Hugging Face | How to use JAX/Flax with Transformers | 5.30pm-6.00pm CEST / 8.30am-9.00am PST | [](https://www.youtube.com/watch?v=__eG63ZP_5g) |
+| Sabrina J. Mielke, Johns Hopkins University & HuggingFace | From stateful code to purified JAX: how to build your neural net framework | 6.00pm-6.30pm CEST / 9.00am-9.30am PST | [](https://youtu.be/__eG63ZP_5g?t=1576) |
+| Mostafa Dehghani, Google Brain | Long Range Arena: Benchmarking Efficient Transformers | 6.30pm-7.00pm CEST / 9.30am-10.00am PST | [](https://youtu.be/__eG63ZP_5g?t=3695) |
+| Rohan Anil, Google Brain | Scalable Second Order Optimization for Deep Learning | 7.00pm-7.30pm CEST / 10.00am-10.30am PST | [](https://youtu.be/__eG63ZP_5g?t=5285) |
+
+
+### Friday, July 2nd
+- [Watch the talks on YouTube](https://www.youtube.com/watch?v=ZCMOPkcTu3s)
+- [Chat history](https://docs.google.com/spreadsheets/d/1PZ5xYV2hVwlAVQSqDag65ympv5YNCSDmXyG-eWTaZ_o/edit#gid=1166061401)
+
+ Speaker | Topic | Time | Video |
+|-------------|---------------------------------|------------------------|------------------------|
+| Lucas Beyer, Google Brain | Vision Transformer | 5.00pm-5.30 CEST / 8.00am-8.30 PST | [](https://www.youtube.com/watch?v=ZCMOPkcTu3s) |
+| Ben Wang, EleutherAI | Multihost Training in Mesh Transformer JAX | 5.30pm-6.00 CEST / 8.30am-9.00 PST | [](https://youtu.be/ZCMOPkcTu3s?t=1803) |
+| Iurii Kemaev, Soňa Mokrá, Junhyuk Oh, DeepMind | DeepMind JAX Ecosystem | 6.00pm-6.30 CEST / 9.00am-9.30am PST | [](https://youtu.be/ZCMOPkcTu3s?t=3388) |
+| Siddhartha Kamalakara, Joanna Yoo & João G M Araújo, Cohere | Training large scale language models | 6:30pm-7.00pm CEST / 9:30am-10.00am PST | [](https://youtu.be/ZCMOPkcTu3s?t=5095) |
+
+### Talks & Speakers
+
+#### Skye Wanderman-Milne, JAX developer, Google Brain
+- Talk: Intro to JAX on Cloud TPUs
+- Abstract: JAX is a system for high-performance machine-learning research that combines the familiarity of Python + NumPy together with the power of hardware acceleration on CPUs, GPUs, and TPUs. It offers composable function transformations for automatic differentiation, automatic batching, end-to-end compilation, and both data and model parallelism. This talk will show you how to get up and running with JAX on a Cloud TPU VM.
+- Speaker info: Skye Wanderman-Milne is a software engineer working on JAX. She has previously worked on TensorFlow and Apache Impala, a high-performance distributed database.
+
+#### Marc van Zee, Research SWE, Google Brain (Flax team)
+- Talk: Introduction to Flax
+- Abstract: In this talk I will provide a high-level introduction to the neural network library Flax. I will discuss the Flax philosophy, talk about the ecosystem around Flax and provide a high-level introduction to the code. I explain the Module abstraction and how to use it to train your models.
+- Speaker info: Marc is at Google Research for over 4 years. First he worked on conceptual AI, developing a next generation language understanding and reasoning prototype and he authored the CFQ dataset for compositional generalization. Currently, Marc works as a research software engineer in the Flax team.
+
+#### Pablo Castro, Staff Research Software Developer; Google Research, Brain Team
+- Talk: Using Jax & Flax for RL with the Dopamine library
+- Abstract: The Dopamine library was launched with TensorFlow in 2018 and we added a Jax/Flax variant of it last year. Internally, Jax's flexibility has facilitated our RL research tremendously, and we are excited to demonstrate its potential.
+- Speaker info: Pablo Samuel has been at Google for over 9 years, and is currently a researcher with the Brain team, focusing on fundamental reinforcement learning, as well as machine learning and creativity. Aside from his research, Pablo Samuel is an active musician (with a channel exploring the intersection of music and computer science), and is helping increase the representation of the LatinX community in the research world.
+- Dopamine repo: https://github.com/google/dopamine
+- Homepage: https://psc-g.github.io/
+- Twitter: https://twitter.com/pcastr
+
+#### Suraj Patil & Patrick von Platen, Machine Learning Engineers at Hugging Face
+- Talk: How to use JAX/Flax with Transformers
+- Abstract: Transformers is one of the most popular open-source ML libraries and supports PyTorch, Tensorflow, and JAX/Flax. In this talk, we will explain how JAX/Flax models should be used in Transformers and compare their design in Transformers with the design of PyTorch models in Transformers. In the second part, we will give you a hands-on presentation of how a model can be trained end-to-end with the official JAX/Flax example scripts using Transformers & Datasets. Along the way, we want to give you some tips and tricks on how to best realize your project.
+- Speaker info: Suraj and Patrick are part of Hugging Face’s open source team and lead the integration of JAX/Flax into Transformers.
+- GitHub: https://github.com/patil-suraj & https://github.com/patrickvonplaten
+
+#### Sabrina J. Mielke, PhD student at The Johns Hopkins University & Part-time research intern at HuggingFace
+- Talk: From stateful code to purified JAX: how to build your neural net framework
+- Abstract: Moving from object-oriented (and stateful) PyTorch- or TF2-code with tape-based backprop to JAX isn't easy---and while running grad() on numpy-oneliners is cool and all, you do wonder... how do I build actual big neural nets? Libraries like flax, trax, or haiku make it easy---but how could you build machinery like that yourself?
+- Speaker info: Sabrina is a PhD student at the Johns Hopkins University and a part-time research intern at HuggingFace, researching open-vocabulary language models for segmentation and tokenization. She has published and co-organized workshops and shared tasks on these topics as well as on morphology and typological analysis in ACL, NAACL, EMNLP, LREC, and AAAI. You can find her reminisce for a time when formal language theory played a bigger role in NLP on Twitter at @sjmielke.
+- Links: The 2020 blogpost this talk will be based on: https://sjmielke.com/jax-purify.htm, leading to our experiment Parallax and eventually Haiku
+
+#### Mostafa Dehghani, Research Scientist, Google Brain
+- Talk: Long Range Arena: Benchmarking Efficient Transformers
+- Abstract: Transformers do not scale very well to long sequence lengths largely because of quadratic self-attention complexity. In the recent months, a wide spectrum of efficient, fast Transformers have been proposed to tackle this problem, more often than not claiming superior or comparable model quality to vanilla Transformer models. So, we now need a well-established consensus on how to evaluate this class of models. Moreover, inconsistent benchmarking on a wide spectrum of tasks and datasets makes it difficult to assess relative model quality amongst many models. I'll talk about a systematic and unified benchmark, LRA, specifically focused on evaluating model quality under long-context scenarios. LRA is a suite of tasks consisting of sequences ranging from 1K to 16K tokens, encompassing a wide range of data types and modalities such as text, natural, synthetic images, and mathematical expressions requiring similarity, structural, and visual-spatial reasoning. We systematically evaluate ten well-established long-range Transformer models (Reformers, Linformers, Linear Transformers, Sinkhorn Transformers, Performers, Synthesizers, Sparse Transformers, and Longformers) on LRA. LRA paves the way towards better understanding this class of efficient Transformer models, facilitates more research in this direction, and presents new challenging tasks to tackle.
+- Speaker info: https://mostafadehghani.com/
+
+#### Rohan Anil, Senior Staff Software Engineer, Google Research, Brain Team
+- Talk: Scalable Second Order Optimization for Deep Learning
+- Abstract: Optimization in machine learning, both theoretical and applied, is presently dominated by first-order gradient methods such as stochastic gradient descent. Second-order optimization methods, that involve second derivatives and/or second order statistics of the data, are far less prevalent despite strong theoretical properties, due to their prohibitive computation, memory and communication costs. In an attempt to bridge this gap between theoretical and practical optimization, we present a scalable implementation of a second-order preconditioned method (concretely, a variant of full-matrix Adagrad), that along with several critical algorithmic and numerical improvements, provides significant convergence and wall-clock time improvements compared to conventional first-order methods on state-of-the-art deep models. Our novel design effectively utilizes the prevalent heterogeneous hardware architecture for training deep models, consisting of a multicore CPU coupled with multiple accelerator units. We demonstrate superior performance compared to state-of-the-art on very large learning tasks such as machine translation with Transformers, language modeling with BERT, click-through rate prediction on Criteo, and image classification on ImageNet with ResNet-50.
+- Speaker info: Rohan Anil is a software engineer at Google Research, Mountain View. Lately, he has been working on scalable and practical optimization techniques for efficient training of neural networks in various regimes.
+- Resources:
+ - https://arxiv.org/abs/2002.09018
+ - https://arxiv.org/abs/1901.11150
+ - https://arxiv.org/abs/2106.06199
+
+
+#### Lucas Beyer, Senior Research Engineer, Google Brain
+- Talk: Vision Transformer
+- Abstract: This talk will discuss the learning of general visual representations via large-scale pre-training and few-shot transfer, with a special focus on the Vision Transformer (ViT) architecture, which popularized transformers for the visual domain.
+- Speaker info: Lucas Beyer is a self-taught hacker and studied engineer. He went on to do his PhD in robotic perception at RWTH Aachen and is currently on a quest to find the ultimate visual representation at Google Brain in Zürich
+
+#### Ben Wang, Independent AI Researcher, EleutherAI
+- Talk: Multihost Training in Mesh Transformer JAX
+- Abstract: As models become larger, training must be scaled across multiple nodes. This talk discusses some design decisions and tradeoffs made for scaling to multiple nodes in Mesh Transformer JAX, a library for running model parallel transformers on TPU pods.
+- Speaker info: Ben is an independent AI researcher who contributes to EleutherAI, an open source research collective centered around democratizing access to powerful AI models. Recently he has released GPT-J-6B, a 6 billion parameter transformer which is the most powerful autoregressive language model in terms of zero-shot performance with public weights.
+- Website: https://www.eleuther.ai/
+
+#### Iurii Kemaev, Research Engineer, Soňa Mokrá, Research Engineer, and Junhyuk Oh, Research Scientist, DeepMind
+- Talk: DeepMind JAX Ecosystem
+- Abstract: The DeepMind JAX Ecosystem is an effort to build a shared substrate of components to enable all aspects of AGI Research. In this talk, our researchers and engineers will give a high-level overview of our Ecosystem goals and design philosophies, using our Haiku (neural network), Optax (optimization) and RLax (reinforcement learning) libraries as examples. We will then deep dive on two examples of recent DeepMind research that have been enabled by JAX and these libraries: generative models and meta-gradient reinforcement learning.
+- Speaker info:
+ - Iurii Kemaev is a Research Engineer at DeepMind. He has been using JAX for 2 years advancing RL research. Iurii is one of the DM JAX ecosystem leads.
+ - Soňa Mokrá is a Research Engineer at DeepMind. She has a background in machine translation and has been using JAX as the main ML framework for the past 6 months.
+ - Junhyuk Oh is a Research Scientist at DeepMind, working on reinforcement learning and meta-learning. More information is available at https://junhyuk.com/
+
+#### Siddhartha Kamalakara, Joanna Yoo, João G M Araújo, MLE at Cohere
+- Talk: Training large scale language models
+- Abstract: A journey through Cohere’s experiences with training large scale language models. Join us in our exploration of pipeline and model parallelism as strategies for efficient training of large language models. We will present and motivate our recent transition to JAX+Flax as our choice of internal tech stack.
+- Speaker info:
+ - João G M Araújo is a Brazilian college student with a passion for mathematics and a fascination for Deep Learning. João conducted research on representation learning and spent 3 months in Japan working on NeuroEvolution. João likes reading fantasy books and spending quality time with family and friends, and also runs a YouTube series on theoretical understanding of Deep Learning where researchers talk about their findings
+ - Joanna Yoo is one of the founding engineers at Cohere, working on scaling language models for the last year and half. Joanna loves live concerts and rock climbing!
+ - Siddhartha Rao Kamalakara is an MLE at Cohere and a researcher at FOR.ai with research interests at the intersection of efficient training and empirical understanding of DL.
+- Website: https://cohere.ai/
+
+
+## How to use the hub for collaboration
+
+In this section, we will explain how a team can use the 🤗 hub to collaborate on a project.
+The 🤗 hub allows each team to create a repository with integrated git version control that
+should be used for their project.
+The advantages of using a repository on the 🤗 hub are:
+
+- easy collaboration - each team member has write access to the model repository
+- integrated git version control - code scripts as well as large model files are tracked using git version control
+- easy sharing - the hub allows each team to easily share their work during and after the event
+- integrated tensorboard functionality - uploaded tensorboard traces are automatically displayed on an integrated tensorboard tab
+
+We highly recommend each team to make use of the 🤗 hub during the event.
+To better understand how the repository and the hub in general functions, please take a look at the documentation and the videos [here](https://huggingface.co/docs/hub).
+
+Now let's explain in more detail how a project can be created on the hub. Having an officially defined project on [this](https://docs.google.com/spreadsheets/d/1GpHebL7qrwJOc9olTpIPgjf8vOS0jNb6zR_B8x_Jtik/edit?usp=sharing) Google Sheet you should be part of [the Flax Community organization on the hub](https://huggingface.co/flax-community). All repositories should be created under this organization so that write access can be shared and everybody can easily access other participants'
+work 🤗. Note that we are giving each team member access to all repositories created under [flax-community](https://huggingface.co/flax-community), but we encourage participants to only clone and edit repositories corresponding to one's teams. If you want to help other teams, please ask them before changing files in their repository! The integrated git version control keeps track of
+all changes, so in case a file was deleted by mistake, it is trivial to re-create it.
+
+Awesome! Now, let's first go over a simple example where most of the required we'll pre-train a RoBERTa model on a low-resource language. To begin with, we create a repository
+under [the Flax Community organization on the hub](https://huggingface.co/flax-community) by logging in to the hub and going to [*"Add model"*](https://huggingface.co/new). By default
+the username should be displayed under "*Owner*", which we want to change to *flax-community*. Next, we give our repository a fitting name for the project - here we'll just call it
+*roberta-base-als* because we'll be pretraining a RoBERTa model on the super low-resource language *Alemannic* (`als`). We make sure that the model is a public repository and create it!
+It should then be displayed on [the Flax Community organization on the hub](https://huggingface.co/flax-community).
+
+Great, now we have a project directory with integrated git version control and a public model page, which we can access under [flax-community/roberta-base-als](https://huggingface.co/flax-community/roberta-base-als). Let's create a short README so that other participants know what this model is about. You can create the README.md directly on the model page as a markdown file.
+Let's now make use of the repository for training.
+
+We assume that the 🤗 Transformers library and [git-lfs](https://git-lfs.github.com/) are correctly installed on our machine or the TPU attributed to us.
+If this is not the case, please refer to the [Installation guide](#how-to-install-relevant-libraries) and the official [git-lfs](https://git-lfs.github.com/) website.
+
+At first we should log in:
+
+```bash
+$ huggingface-cli login
+```
+
+Next we can clone the repo:
+
+```bash
+$ git clone https://huggingface.co/flax-community/roberta-base-als
+```
+
+We have now cloned the model's repository and it should be under `roberta-base-als`. As you can see,
+we have all the usual git functionalities in this repo - when adding a file, we can do `git add .`, `git commit -m "add file"` and `git push`
+as usual. Let's try it out by adding the model's config.
+
+We go into the folder:
+
+```bash
+$ cd ./roberta-base-als
+```
+
+and run the following commands in a Python shell to save a config.
+
+```python
+from transformers import RobertaConfig
+
+config = RobertaConfig.from_pretrained("FacebookAI/roberta-base")
+config.save_pretrained("./")
+```
+
+Now we've added a `config.json` file and can upload it by running
+
+```bash
+$ git add . && git commit -m "add config" && git push
+```
+
+Cool! The file is now displayed on the model page under the [files tab](https://huggingface.co/flax-community/roberta-base-als/tree/main).
+We encourage you to upload all files except maybe the actual data files to the repository. This includes training scripts, model weights,
+model configurations, training logs, etc...
+
+Next, let's create a tokenizer and save it to the model dir by following the instructions of the [official Flax MLM README](https://github.com/huggingface/transformers/tree/main/examples/flax/language-modeling#train-tokenizer). We can again use a simple Python shell.
+
+```python
+from datasets import load_dataset
+from tokenizers import ByteLevelBPETokenizer
+
+# load dataset
+dataset = load_dataset("oscar", "unshuffled_deduplicated_als", split="train")
+
+# Instantiate tokenizer
+tokenizer = ByteLevelBPETokenizer()
+
+def batch_iterator(batch_size=1000):
+ for i in range(0, len(dataset), batch_size):
+ yield dataset[i: i + batch_size]["text"]
+
+# Customized training
+tokenizer.train_from_iterator(batch_iterator(), vocab_size=50265, min_frequency=2, special_tokens=[
+ "",
+ "",
+ " ",
+ "",
+ "",
+])
+
+# Save files to disk
+tokenizer.save("./tokenizer.json")
+```
+
+This creates and saves our tokenizer directly in the cloned repository.
+Finally, we can start training. For now, we'll simply use the official [`run_mlm_flax`](https://github.com/huggingface/transformers/blob/main/examples/flax/language-modeling/run_mlm_flax.py)
+script, but we might make some changes later. So let's copy the script into our model repository.
+
+```bash
+$ cp ~/transformers/examples/flax/language-modeling/run_mlm_flax.py ./
+```
+
+This way we are certain to have all the code used to train the model tracked in our repository.
+Let's start training by running:
+
+```bash
+./run_mlm_flax.py \
+ --output_dir="./" \
+ --model_type="roberta" \
+ --config_name="./" \
+ --tokenizer_name="./" \
+ --dataset_name="oscar" \
+ --dataset_config_name="unshuffled_deduplicated_als" \
+ --max_seq_length="128" \
+ --per_device_train_batch_size="4" \
+ --per_device_eval_batch_size="4" \
+ --learning_rate="3e-4" \
+ --warmup_steps="1000" \
+ --overwrite_output_dir \
+ --num_train_epochs="8" \
+ --push_to_hub
+```
+
+Since the dataset is tiny this command should actually run in less than 5 minutes. Note that we attach
+the flag ``--push_to_hub`` so that both model weights and tensorboard traces are automatically uploaded to the hub.
+You can see the tensorboard directly on the model page, under the [Training metrics tab](https://huggingface.co/flax-community/roberta-base-als/tensorboard).
+
+As you can see, it is pretty simple to upload model weights and training logs to the model hub. Since the repository
+has git version control, you & your team probably already have the necessary skills to collaborate. Thanks
+to `git-lfs` being integrated into the hub, model weights and other larger file can just as easily be uploaded
+and changed. Finally, at Hugging Face, we believe that the model hub is a great platform to share your project
+while you are still working on it:
+
+- Bugs in training scripts can be found and corrected by anybody participating in the event
+- Loss curves can be analyzed directly on the model page
+- Model weights can be accessed and analyzed by everybody from the model repository
+
+If you are not using a transformers model, don't worry - you should still be able to make use of the hub's functionalities!
+The [huggingface_hub](https://github.com/huggingface/huggingface_hub) allows you to upload essentially any JAX/Flax model to the hub with
+just a couple of lines of code. *E.g.* assuming you want to call your model simply `flax-model-dummy`, you can upload it to the hub with
+just three lines of code:
+
+
+```python
+from flax import serialization
+from jax import random
+from flax import linen as nn
+from huggingface_hub import Repository
+
+model = nn.Dense(features=5)
+
+key1, key2 = random.split(random.PRNGKey(0))
+x = random.normal(key1, (10,))
+params = model.init(key2, x)
+
+bytes_output = serialization.to_bytes(params)
+
+repo = Repository("flax-model", clone_from="flax-community/flax-model-dummy", token=True)
+with repo.commit("My cool Flax model :)"):
+ with open("flax_model.msgpack", "wb") as f:
+ f.write(bytes_output)
+
+# Repo is created and available here: https://huggingface.co/flax-community/flax-model-dummy
+```
+
+**Note**: Make sure to have `huggingface_hub >= 0.0.13` to make this command work.
+
+For more information, check out [this PR](https://github.com/huggingface/huggingface_hub/pull/143) on how to upload any framework to the hub.
+
+## How to setup TPU VM
+
+In this section we will explain how you can ssh into a TPU VM that has been given to your team.
+If your username is in one of the officially defined projects [here](https://docs.google.com/spreadsheets/d/1GpHebL7qrwJOc9olTpIPgjf8vOS0jNb6zR_B8x_Jtik/edit?usp=sharing), you should have received two emails:
+
+- one that states that you have been granted the role "Community Week Participants" for the project hf-flax, and
+- one (or more if you are in multiple projects) that gives you the TPU name and the TPU zone for the TPU of your team
+
+You should click on "Open Cloud Console" on the first mail and agree to the pop up windows that follows. It will allow you to use a TPU VM. Don't worry if you cannot access the actual project `hf-flax` visually on the google cloud console and receive an error:
+
+```
+You don't have sufficient permission to view this page
+```
+- this is expected!
+
+Great, now you and your team can access your TPU VM!
+
+In the following, we will describe how to do so using a standard console, but you should also be able to connect to the TPU VM via IDEs, like Visual Studio Code, etc.
+
+1. You need to install the Google Cloud SDK. Please follow the instructions on [cloud.google.com/sdk](https://cloud.google.com/sdk/docs/install#linux).
+
+2. Once you've installed the google cloud sdk, you should set your account by running the following command. Make sure that `` corresponds to the gmail address you used to sign up for this event.
+
+```bash
+$ gcloud config set account
+```
+
+3. Let's also make sure the correct project is set in case your email is used for multiple gcloud projects:
+
+```bash
+$ gcloud config set project hf-flax
+```
+
+4. Next, you will need to authenticate yourself. You can do so by running:
+
+```bash
+$ gcloud auth login
+```
+
+This should give you a link to a website, where you can authenticate your gmail account.
+
+5. Finally, you can ssh into the TPU VM! Please run the following command by setting to either `europe-west4-a` or `us-central1-a` (depending on what is stated in the second email you received) and to the TPU name also sent to you in the second email.
+
+```bash
+$ gcloud alpha compute tpus tpu-vm ssh --zone --project hf-flax
+```
+
+This should ssh you into the TPU VM!
+Now you can follow the steps of the section [How to install relevant libraries](#how-to-install-relevant-libraries) to install all necessary
+libraries. Make sure to carefully follow the explanations of the "**IMPORTANT**" statement to correctly install JAX on TPU.
+Also feel free to install other `python` or `apt` packages on your machine if it helps you to work more efficiently!
+
+
+## How to build a demo
+
+### Using the Hugging Face Widgets
+
+Hugging Face has over [15 widgets](https://huggingface-widgets.netlify.app/) for different use cases using 🤗 Transformers library. Some of them also support [3rd party libraries](https://huggingface.co/docs/hub/libraries) such as [Sentence Similarity](https://huggingface.co/sentence-transformers/paraphrase-xlm-r-multilingual-v1) with Sentence Transformers and [Text to Speech](https://huggingface.co/julien-c/ljspeech_tts_train_tacotron2_raw_phn_tacotron_g2p_en_no_space_train) with [ESPnet](https://github.com/espnet/espnet).
+
+All the widgets are open sourced in the `huggingface_hub` [repo](https://github.com/huggingface/huggingface_hub/tree/main/widgets). Here is a summary of existing widgets:
+
+**NLP**
+* **Conversational:** To have the best conversations!. [Example](https://huggingface.co/microsoft/DialoGPT-large?).
+* **Feature Extraction:** Retrieve the input embeddings. [Example](https://huggingface.co/sentence-transformers/distilbert-base-nli-mean-tokens?text=test).
+* **Fill Mask:** Predict potential words for a mask token. [Example](https://huggingface.co/google-bert/bert-base-uncased?).
+* **Question Answering:** Given a context and a question, predict the answer. [Example](https://huggingface.co/google-bert/bert-large-uncased-whole-word-masking-finetuned-squad).
+* **Sentence Simmilarity:** Predict how similar a set of sentences are. Useful for Sentence Transformers.
+* **Summarization:** Given a text, output a summary of it. [Example](https://huggingface.co/sshleifer/distilbart-cnn-12-6).
+* **Table Question Answering:** Given a table and a question, predict the answer. [Example](https://huggingface.co/google/tapas-base-finetuned-wtq).
+* **Text Generation:** Generate text based on a prompt. [Example](https://huggingface.co/openai-community/gpt2)
+* **Token Classification:** Useful for tasks such as Named Entity Recognition and Part of Speech. [Example](https://huggingface.co/dslim/bert-base-NER).
+* **Zero-Shot Classification:** Too cool to explain with words. Here is an [example](https://huggingface.co/typeform/distilbert-base-uncased-mnli)
+* ([WIP](https://github.com/huggingface/huggingface_hub/issues/99)) **Table to Text Generation**.
+
+**Speech**
+* **Audio to Audio:** For tasks such as audio source separation or speech enhancement.
+* **Automatic Speech Recognition:** Convert audio to text. [Example](https://huggingface.co/facebook/wav2vec2-base-960h)
+* **Text to Speech**: Convert text to audio.
+
+**Image**
+* **Image Classification:** Given an image, predict its class. [Example](https://huggingface.co/osanseviero/llamastic).
+* ([WIP](https://github.com/huggingface/huggingface_hub/issues/100)) **Zero Shot Image Classification**
+* ([WIP](https://github.com/huggingface/huggingface_hub/issues/112)) **Image Captioning**
+* ([WIP](https://github.com/huggingface/huggingface_hub/issues/113)) **Text to Image Generation**
+* ([Proposed](https://github.com/huggingface/huggingface_hub/issues/127)) **Visual Question Answering**
+
+You can propose and implement new widgets by [opening an issue](https://github.com/huggingface/huggingface_hub/issues). Contributions are welcomed!
+
+
+### Using a Streamlit demo
+
+Sometimes you might be using different libraries or a very specific application that is not well supported by the current widgets. In this case, [Streamlit](https://streamlit.io/) can be an excellent option to build a cool visual demo. Setting up a Streamlit application is straightforward and in Python!
+
+A common use case is how to load files you have in your model repository in the Hub from the Streamlit demo. The `huggingface_hub` library is here to help you!
+
+```bash
+pip install huggingface_hub
+```
+
+Here is an example downloading (and caching!) a specific file directly from the Hub
+```python
+from huggingface_hub import hf_hub_download
+filepath = hf_hub_download("flax-community/roberta-base-als", "flax_model.msgpack");
+```
+
+In many cases you will want to download the full repository. Here is an example downloading all the files from a repo. You can even specify specific revisions!
+
+```python
+from huggingface_hub import snapshot_download
+local_path = snapshot_download("flax-community/roberta-base-als");
+```
+
+Note that if you're using 🤗 Transformers library, you can quickly load the model and tokenizer as follows
+```python
+from transformers import AutoTokenizer, AutoModelForMaskedLM
+
+tokenizer = AutoTokenizer.from_pretrained("REPO_ID")
+model = AutoModelForMaskedLM.from_pretrained("REPO_ID")
+```
+
+
+We'll provide more examples on Streamlit demos next week. Stay tuned!
+
+### Using a Gradio demo
+
+You can also use [Gradio](https://gradio.app/) to share your demos! [Here](https://huggingface.co/blog/gradio) is an example using the Gradio library to create a GUI for a Hugging Face model.
+
+More to come!
+
+## Project evaluation
+
+For your project to be evaluated, please fill out [this google form](https://forms.gle/jQaMkj3JJdD4Xcwn9).
+Please make sure that your submitted project includes a demo as well as information about the model, data, training methods, etc.
+
+### Criteria
+
+* **Demo.** All projects are required to have a demo. It’s open ended, but we provide some ideas on how to build demos in the [How to build a demo](#how-to-build-a-demo) section.
+* **Technical difficulty.** Difficulty has different aspects, such as working with complex architectures, obtaining better evaluation metrics than existing models, or implementing models for low-resource languages.
+* **Social impact.** The project is expected to have a positive social impact, e.g. by tackling under-explored area of practical interest for minorities or under-represented group (low-ressources languages, specific focus on bias, fairness or ethical issues in ML) or by tackling general societal challenges, e.g. health or climate related challenges.
+* **Innovativeness.** Projects that propose novel applications or bring new ideas will be rewarded more.
+
+### Jury
+
+* [Niki Parmar](https://research.google/people/NikiParmar/): Staff Research Scientist at Google.
+* [Ross Wightman](https://www.linkedin.com/in/wightmanr/): Angel Investor.
+* [Thomas Wolf](https://www.linkedin.com/in/thomas-wolf-a056857/): Co-founder and CSO at Hugging Face.
+* [Ashish Vaswani](https://research.google/people/AshishVaswani/): Staff Research Scientist at Google Brain.
+
+### Process
+
+* **July 17, 12h00 CEST**: TPU VM access closes.
+* **July 19, 12h00 CEST**: Project completition ends (including demo).
+* **July 19-21** A group of event organizers (Suraj, Patrick, Suzana, and Omar) will do an initial filter to find the top 15 projects.
+* **July 22-26** The jury will go over the 15 projects and pick the top three projects out of them.
+* **July 27.** Winner projects are announced
+
+
+## General tips and tricks
+
+TODO (will be filled continuously)...
+
+## FAQ
+
+TODO (will be filled continuously)...
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..42586e49580ebba3f9143d9303536f3c1580db5b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/README.md
@@ -0,0 +1,60 @@
+
+Author: [@vasudevgupta7](https://github.com/thevasudevgupta/)
+
+## Intro
+
+In this project, we fine-tuned [**BigBird**](https://arxiv.org/abs/2007.14062) on [**natural-questions**](https://huggingface.co/datasets/natural_questions) dataset for **question-answering** task on long documents. **BigBird**, is a **sparse-attention based transformer** which extends Transformer based models, such as BERT to much **longer sequences**.
+
+Read more about BigBird at https://huggingface.co/blog/big-bird
+
+## Fine-tuning
+
+**Setup**
+
+You need to install jax yourself by following the official docs ([refer this](https://github.com/google/jax#installation)). Other requirements for this project can be installed by running following command:
+
+```shell
+pip3 install -qr requirements.txt
+```
+
+**Download & prepare dataset**
+
+The Natural Questions corpus contains questions from real users, and it requires QA systems to read and comprehend an entire Wikipedia article that may or may not contain the answer to the question. This corpus takes ~100 GB on disk. We have used HuggingFace datasets to download & process the dataset.
+
+```shell
+# just run following CMD
+python3 prepare_natural_questions.py
+
+# this will download the whole dataset from HuggingFace Hub & will make it ready for training
+# this script takes ~3 hours to process the dataset
+```
+
+**Launch Training**
+
+We have trained on Cloud's TPU v3-8. Each epoch took around 4.5 hours and the model got converged in just 2 epochs. You can see complete training args in [this script](bigbird_flax.py).
+
+```shell
+# just run following CMD
+python3 train.py
+
+# In case, you want to try hparams tuning, you can run wandb sweep
+wandb sweep --project=bigbird sweep_flax.yaml
+wandb agent
+```
+
+## Evaluation
+
+Our evaluation script is different from the original script and we are evaluating sequences with length up to 4096 for simplicity. We managed to get the **EM score of ~55.2** using our evaluation script.
+
+```shell
+# download validation-dataset first
+mkdir natural-questions-validation
+wget https://huggingface.co/datasets/vasudevgupta/natural-questions-validation/resolve/main/natural_questions-validation.arrow -P natural-questions-validation
+wget https://huggingface.co/datasets/vasudevgupta/natural-questions-validation/resolve/main/dataset_info.json -P natural-questions-validation
+wget https://huggingface.co/datasets/vasudevgupta/natural-questions-validation/resolve/main/state.json -P natural-questions-validation
+
+# simply run following command
+python3 evaluate.py
+```
+
+You can find our checkpoint on HuggingFace Hub ([see this](https://huggingface.co/vasudevgupta/flax-bigbird-natural-questions)). In case you are interested in PyTorch BigBird fine-tuning, you can refer to [this repository](https://github.com/thevasudevgupta/bigbird).
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/bigbird_flax.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/bigbird_flax.py
new file mode 100644
index 0000000000000000000000000000000000000000..af5e11c83a6ad2f4f2afa55f316c4e06b493b351
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/bigbird_flax.py
@@ -0,0 +1,323 @@
+import json
+import os
+from dataclasses import dataclass
+from functools import partial
+from typing import Callable
+
+import flax.linen as nn
+import jax
+import jax.numpy as jnp
+import joblib
+import optax
+import wandb
+from flax import jax_utils, struct, traverse_util
+from flax.serialization import from_bytes, to_bytes
+from flax.training import train_state
+from flax.training.common_utils import shard
+from tqdm.auto import tqdm
+
+from transformers import BigBirdConfig, FlaxBigBirdForQuestionAnswering
+from transformers.models.big_bird.modeling_flax_big_bird import FlaxBigBirdForQuestionAnsweringModule
+
+
+class FlaxBigBirdForNaturalQuestionsModule(FlaxBigBirdForQuestionAnsweringModule):
+ """
+ BigBirdForQuestionAnswering with CLS Head over the top for predicting category
+
+ This way we can load its weights with FlaxBigBirdForQuestionAnswering
+ """
+
+ config: BigBirdConfig
+ dtype: jnp.dtype = jnp.float32
+ add_pooling_layer: bool = True
+
+ def setup(self):
+ super().setup()
+ self.cls = nn.Dense(5, dtype=self.dtype)
+
+ def __call__(self, *args, **kwargs):
+ outputs = super().__call__(*args, **kwargs)
+ cls_out = self.cls(outputs[2])
+ return outputs[:2] + (cls_out,)
+
+
+class FlaxBigBirdForNaturalQuestions(FlaxBigBirdForQuestionAnswering):
+ module_class = FlaxBigBirdForNaturalQuestionsModule
+
+
+def calculate_loss_for_nq(start_logits, start_labels, end_logits, end_labels, pooled_logits, pooler_labels):
+ def cross_entropy(logits, labels, reduction=None):
+ """
+ Args:
+ logits: bsz, seqlen, vocab_size
+ labels: bsz, seqlen
+ """
+ vocab_size = logits.shape[-1]
+ labels = (labels[..., None] == jnp.arange(vocab_size)[None]).astype("f4")
+ logits = jax.nn.log_softmax(logits, axis=-1)
+ loss = -jnp.sum(labels * logits, axis=-1)
+ if reduction is not None:
+ loss = reduction(loss)
+ return loss
+
+ cross_entropy = partial(cross_entropy, reduction=jnp.mean)
+ start_loss = cross_entropy(start_logits, start_labels)
+ end_loss = cross_entropy(end_logits, end_labels)
+ pooled_loss = cross_entropy(pooled_logits, pooler_labels)
+ return (start_loss + end_loss + pooled_loss) / 3
+
+
+@dataclass
+class Args:
+ model_id: str = "google/bigbird-roberta-base"
+ logging_steps: int = 3000
+ save_steps: int = 10500
+
+ block_size: int = 128
+ num_random_blocks: int = 3
+
+ batch_size_per_device: int = 1
+ max_epochs: int = 5
+
+ # tx_args
+ lr: float = 3e-5
+ init_lr: float = 0.0
+ warmup_steps: int = 20000
+ weight_decay: float = 0.0095
+
+ save_dir: str = "bigbird-roberta-natural-questions"
+ base_dir: str = "training-expt"
+ tr_data_path: str = "data/nq-training.jsonl"
+ val_data_path: str = "data/nq-validation.jsonl"
+
+ def __post_init__(self):
+ os.makedirs(self.base_dir, exist_ok=True)
+ self.save_dir = os.path.join(self.base_dir, self.save_dir)
+ self.batch_size = self.batch_size_per_device * jax.device_count()
+
+
+@dataclass
+class DataCollator:
+ pad_id: int
+ max_length: int = 4096 # no dynamic padding on TPUs
+
+ def __call__(self, batch):
+ batch = self.collate_fn(batch)
+ batch = jax.tree_util.tree_map(shard, batch)
+ return batch
+
+ def collate_fn(self, features):
+ input_ids, attention_mask = self.fetch_inputs(features["input_ids"])
+ batch = {
+ "input_ids": jnp.array(input_ids, dtype=jnp.int32),
+ "attention_mask": jnp.array(attention_mask, dtype=jnp.int32),
+ "start_labels": jnp.array(features["start_token"], dtype=jnp.int32),
+ "end_labels": jnp.array(features["end_token"], dtype=jnp.int32),
+ "pooled_labels": jnp.array(features["category"], dtype=jnp.int32),
+ }
+ return batch
+
+ def fetch_inputs(self, input_ids: list):
+ inputs = [self._fetch_inputs(ids) for ids in input_ids]
+ return zip(*inputs)
+
+ def _fetch_inputs(self, input_ids: list):
+ attention_mask = [1 for _ in range(len(input_ids))]
+ while len(input_ids) < self.max_length:
+ input_ids.append(self.pad_id)
+ attention_mask.append(0)
+ return input_ids, attention_mask
+
+
+def get_batched_dataset(dataset, batch_size, seed=None):
+ if seed is not None:
+ dataset = dataset.shuffle(seed=seed)
+ for i in range(len(dataset) // batch_size):
+ batch = dataset[i * batch_size : (i + 1) * batch_size]
+ yield dict(batch)
+
+
+@partial(jax.pmap, axis_name="batch")
+def train_step(state, drp_rng, **model_inputs):
+ def loss_fn(params):
+ start_labels = model_inputs.pop("start_labels")
+ end_labels = model_inputs.pop("end_labels")
+ pooled_labels = model_inputs.pop("pooled_labels")
+
+ outputs = state.apply_fn(**model_inputs, params=params, dropout_rng=drp_rng, train=True)
+ start_logits, end_logits, pooled_logits = outputs
+
+ return state.loss_fn(
+ start_logits,
+ start_labels,
+ end_logits,
+ end_labels,
+ pooled_logits,
+ pooled_labels,
+ )
+
+ drp_rng, new_drp_rng = jax.random.split(drp_rng)
+ grad_fn = jax.value_and_grad(loss_fn)
+ loss, grads = grad_fn(state.params)
+ metrics = jax.lax.pmean({"loss": loss}, axis_name="batch")
+ grads = jax.lax.pmean(grads, "batch")
+
+ state = state.apply_gradients(grads=grads)
+ return state, metrics, new_drp_rng
+
+
+@partial(jax.pmap, axis_name="batch")
+def val_step(state, **model_inputs):
+ start_labels = model_inputs.pop("start_labels")
+ end_labels = model_inputs.pop("end_labels")
+ pooled_labels = model_inputs.pop("pooled_labels")
+
+ outputs = state.apply_fn(**model_inputs, params=state.params, train=False)
+ start_logits, end_logits, pooled_logits = outputs
+
+ loss = state.loss_fn(start_logits, start_labels, end_logits, end_labels, pooled_logits, pooled_labels)
+ metrics = jax.lax.pmean({"loss": loss}, axis_name="batch")
+ return metrics
+
+
+class TrainState(train_state.TrainState):
+ loss_fn: Callable = struct.field(pytree_node=False)
+
+
+@dataclass
+class Trainer:
+ args: Args
+ data_collator: Callable
+ train_step_fn: Callable
+ val_step_fn: Callable
+ model_save_fn: Callable
+ logger: wandb
+ scheduler_fn: Callable = None
+
+ def create_state(self, model, tx, num_train_steps, ckpt_dir=None):
+ params = model.params
+ state = TrainState.create(
+ apply_fn=model.__call__,
+ params=params,
+ tx=tx,
+ loss_fn=calculate_loss_for_nq,
+ )
+ if ckpt_dir is not None:
+ params, opt_state, step, args, data_collator = restore_checkpoint(ckpt_dir, state)
+ tx_args = {
+ "lr": args.lr,
+ "init_lr": args.init_lr,
+ "warmup_steps": args.warmup_steps,
+ "num_train_steps": num_train_steps,
+ "weight_decay": args.weight_decay,
+ }
+ tx, lr = build_tx(**tx_args)
+ state = train_state.TrainState(
+ step=step,
+ apply_fn=model.__call__,
+ params=params,
+ tx=tx,
+ opt_state=opt_state,
+ )
+ self.args = args
+ self.data_collator = data_collator
+ self.scheduler_fn = lr
+ model.params = params
+ state = jax_utils.replicate(state)
+ return state
+
+ def train(self, state, tr_dataset, val_dataset):
+ args = self.args
+ total = len(tr_dataset) // args.batch_size
+
+ rng = jax.random.PRNGKey(0)
+ drp_rng = jax.random.split(rng, jax.device_count())
+ for epoch in range(args.max_epochs):
+ running_loss = jnp.array(0, dtype=jnp.float32)
+ tr_dataloader = get_batched_dataset(tr_dataset, args.batch_size, seed=epoch)
+ i = 0
+ for batch in tqdm(tr_dataloader, total=total, desc=f"Running EPOCH-{epoch}"):
+ batch = self.data_collator(batch)
+ state, metrics, drp_rng = self.train_step_fn(state, drp_rng, **batch)
+ running_loss += jax_utils.unreplicate(metrics["loss"])
+ i += 1
+ if i % args.logging_steps == 0:
+ state_step = jax_utils.unreplicate(state.step)
+ tr_loss = running_loss.item() / i
+ lr = self.scheduler_fn(state_step - 1)
+
+ eval_loss = self.evaluate(state, val_dataset)
+ logging_dict = {
+ "step": state_step.item(),
+ "eval_loss": eval_loss.item(),
+ "tr_loss": tr_loss,
+ "lr": lr.item(),
+ }
+ tqdm.write(str(logging_dict))
+ self.logger.log(logging_dict, commit=True)
+
+ if i % args.save_steps == 0:
+ self.save_checkpoint(args.save_dir + f"-e{epoch}-s{i}", state=state)
+
+ def evaluate(self, state, dataset):
+ dataloader = get_batched_dataset(dataset, self.args.batch_size)
+ total = len(dataset) // self.args.batch_size
+ running_loss = jnp.array(0, dtype=jnp.float32)
+ i = 0
+ for batch in tqdm(dataloader, total=total, desc="Evaluating ... "):
+ batch = self.data_collator(batch)
+ metrics = self.val_step_fn(state, **batch)
+ running_loss += jax_utils.unreplicate(metrics["loss"])
+ i += 1
+ return running_loss / i
+
+ def save_checkpoint(self, save_dir, state):
+ state = jax_utils.unreplicate(state)
+ print(f"SAVING CHECKPOINT IN {save_dir}", end=" ... ")
+ self.model_save_fn(save_dir, params=state.params)
+ with open(os.path.join(save_dir, "opt_state.msgpack"), "wb") as f:
+ f.write(to_bytes(state.opt_state))
+ joblib.dump(self.args, os.path.join(save_dir, "args.joblib"))
+ joblib.dump(self.data_collator, os.path.join(save_dir, "data_collator.joblib"))
+ with open(os.path.join(save_dir, "training_state.json"), "w") as f:
+ json.dump({"step": state.step.item()}, f)
+ print("DONE")
+
+
+def restore_checkpoint(save_dir, state):
+ print(f"RESTORING CHECKPOINT FROM {save_dir}", end=" ... ")
+ with open(os.path.join(save_dir, "flax_model.msgpack"), "rb") as f:
+ params = from_bytes(state.params, f.read())
+
+ with open(os.path.join(save_dir, "opt_state.msgpack"), "rb") as f:
+ opt_state = from_bytes(state.opt_state, f.read())
+
+ args = joblib.load(os.path.join(save_dir, "args.joblib"))
+ data_collator = joblib.load(os.path.join(save_dir, "data_collator.joblib"))
+
+ with open(os.path.join(save_dir, "training_state.json"), "r") as f:
+ training_state = json.load(f)
+ step = training_state["step"]
+
+ print("DONE")
+ return params, opt_state, step, args, data_collator
+
+
+def scheduler_fn(lr, init_lr, warmup_steps, num_train_steps):
+ decay_steps = num_train_steps - warmup_steps
+ warmup_fn = optax.linear_schedule(init_value=init_lr, end_value=lr, transition_steps=warmup_steps)
+ decay_fn = optax.linear_schedule(init_value=lr, end_value=1e-7, transition_steps=decay_steps)
+ lr = optax.join_schedules(schedules=[warmup_fn, decay_fn], boundaries=[warmup_steps])
+ return lr
+
+
+def build_tx(lr, init_lr, warmup_steps, num_train_steps, weight_decay):
+ def weight_decay_mask(params):
+ params = traverse_util.flatten_dict(params)
+ mask = {k: (v[-1] != "bias" and v[-2:] != ("LayerNorm", "scale")) for k, v in params.items()}
+ return traverse_util.unflatten_dict(mask)
+
+ lr = scheduler_fn(lr, init_lr, warmup_steps, num_train_steps)
+
+ tx = optax.adamw(learning_rate=lr, weight_decay=weight_decay, mask=weight_decay_mask)
+ return tx, lr
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/evaluate.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/evaluate.py
new file mode 100644
index 0000000000000000000000000000000000000000..3c5123efeba5d61afcd540d569e1be2d3d15109a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/evaluate.py
@@ -0,0 +1,164 @@
+import jax
+import jax.numpy as jnp
+from bigbird_flax import FlaxBigBirdForNaturalQuestions
+from datasets import load_from_disk
+
+from transformers import BigBirdTokenizerFast
+
+
+CATEGORY_MAPPING = {0: "null", 1: "short", 2: "long", 3: "yes", 4: "no"}
+PUNCTUATION_SET_TO_EXCLUDE = set("".join(["‘", "’", "´", "`", ".", ",", "-", '"']))
+
+
+def get_sub_answers(answers, begin=0, end=None):
+ return [" ".join(x.split(" ")[begin:end]) for x in answers if len(x.split(" ")) > 1]
+
+
+def expand_to_aliases(given_answers, make_sub_answers=False):
+ if make_sub_answers:
+ # if answers are longer than one word, make sure a predictions is correct if it coresponds to the complete 1: or :-1 sub word
+ # *e.g.* if the correct answer contains a prefix such as "the", or "a"
+ given_answers = (
+ given_answers + get_sub_answers(given_answers, begin=1) + get_sub_answers(given_answers, end=-1)
+ )
+ answers = []
+ for answer in given_answers:
+ alias = answer.replace("_", " ").lower()
+ alias = "".join(c if c not in PUNCTUATION_SET_TO_EXCLUDE else " " for c in alias)
+ answers.append(" ".join(alias.split()).strip())
+ return set(answers)
+
+
+def get_best_valid_start_end_idx(start_scores, end_scores, top_k=1, max_size=100):
+ best_start_scores, best_start_idx = jax.lax.top_k(start_scores, top_k)
+ best_end_scores, best_end_idx = jax.lax.top_k(end_scores, top_k)
+
+ widths = best_end_idx[:, None] - best_start_idx[None, :]
+ mask = jnp.logical_or(widths < 0, widths > max_size)
+ scores = (best_end_scores[:, None] + best_start_scores[None, :]) - (1e8 * mask)
+ best_score = jnp.argmax(scores).item()
+
+ return best_start_idx[best_score % top_k], best_end_idx[best_score // top_k]
+
+
+def format_dataset(sample):
+ question = sample["question"]["text"]
+ context = sample["document"]["tokens"]["token"]
+ is_html = sample["document"]["tokens"]["is_html"]
+ long_answers = sample["annotations"]["long_answer"]
+ short_answers = sample["annotations"]["short_answers"]
+
+ context_string = " ".join([context[i] for i in range(len(context)) if not is_html[i]])
+
+ # 0 - No ; 1 - Yes
+ for answer in sample["annotations"]["yes_no_answer"]:
+ if answer == 0 or answer == 1:
+ return {
+ "question": question,
+ "context": context_string,
+ "short": [],
+ "long": [],
+ "category": "no" if answer == 0 else "yes",
+ }
+
+ short_targets = []
+ for s in short_answers:
+ short_targets.extend(s["text"])
+ short_targets = list(set(short_targets))
+
+ long_targets = []
+ for s in long_answers:
+ if s["start_token"] == -1:
+ continue
+ answer = context[s["start_token"] : s["end_token"]]
+ html = is_html[s["start_token"] : s["end_token"]]
+ new_answer = " ".join([answer[i] for i in range(len(answer)) if not html[i]])
+ if new_answer not in long_targets:
+ long_targets.append(new_answer)
+
+ category = "long_short" if len(short_targets + long_targets) > 0 else "null"
+
+ return {
+ "question": question,
+ "context": context_string,
+ "short": short_targets,
+ "long": long_targets,
+ "category": category,
+ }
+
+
+def main():
+ dataset = load_from_disk("natural-questions-validation")
+ dataset = dataset.map(format_dataset).remove_columns(["annotations", "document", "id"])
+ print(dataset)
+
+ short_validation_dataset = dataset.filter(lambda x: (len(x["question"]) + len(x["context"])) < 4 * 4096)
+ short_validation_dataset = short_validation_dataset.filter(lambda x: x["category"] != "null")
+
+ model_id = "vasudevgupta/flax-bigbird-natural-questions"
+ model = FlaxBigBirdForNaturalQuestions.from_pretrained(model_id)
+ tokenizer = BigBirdTokenizerFast.from_pretrained(model_id)
+
+ @jax.jit
+ def forward(*args, **kwargs):
+ start_logits, end_logits, pooled_logits = model(*args, **kwargs)
+ return start_logits, end_logits, jnp.argmax(pooled_logits, axis=-1)
+
+ def evaluate(example):
+ # encode question and context so that they are separated by a tokenizer.sep_token and cut at max_length
+ inputs = tokenizer(
+ example["question"],
+ example["context"],
+ return_tensors="np",
+ max_length=4096,
+ padding="max_length",
+ truncation=True,
+ )
+
+ start_scores, end_scores, category = forward(**inputs)
+
+ predicted_category = CATEGORY_MAPPING[category.item()]
+
+ example["targets"] = example["long"] + example["short"]
+ if example["category"] in ["yes", "no", "null"]:
+ example["targets"] = [example["category"]]
+ example["has_tgt"] = example["category"] != "null"
+ # Now target can be: "yes", "no", "null", "list of long & short answers"
+
+ if predicted_category in ["yes", "no", "null"]:
+ example["output"] = [predicted_category]
+ example["match"] = example["output"] == example["targets"]
+ example["has_pred"] = predicted_category != "null"
+ return example
+
+ max_size = 38 if predicted_category == "short" else 1024
+ start_score, end_score = get_best_valid_start_end_idx(
+ start_scores[0], end_scores[0], top_k=8, max_size=max_size
+ )
+
+ input_ids = inputs["input_ids"][0].tolist()
+ example["output"] = [tokenizer.decode(input_ids[start_score : end_score + 1])]
+
+ answers = expand_to_aliases(example["targets"], make_sub_answers=True)
+ predictions = expand_to_aliases(example["output"])
+
+ # some preprocessing to both prediction and answer
+ answers = {"".join(a.split()) for a in answers}
+ predictions = {"".join(p.split()) for p in predictions}
+ predictions = {s for s in predictions if s not in ["``", "''", "`", "'"]}
+
+ # if there is a common element, it's a exact match
+ example["match"] = len(list(answers & predictions)) > 0
+ example["has_pred"] = predicted_category != "null" and len(predictions) > 0
+
+ return example
+
+ short_validation_dataset = short_validation_dataset.map(evaluate)
+
+ total = len(short_validation_dataset)
+ matched = len(short_validation_dataset.filter(lambda x: x["match"] == 1))
+ print("EM score:", (matched / total) * 100, "%")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/prepare_natural_questions.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/prepare_natural_questions.py
new file mode 100644
index 0000000000000000000000000000000000000000..ebbb184ccb6b6ba7f29c16b0a903958bb365f62b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/prepare_natural_questions.py
@@ -0,0 +1,329 @@
+import os
+
+import jsonlines
+import numpy as np
+from tqdm import tqdm
+
+
+DOC_STRIDE = 2048
+MAX_LENGTH = 4096
+SEED = 42
+PROCESS_TRAIN = os.environ.pop("PROCESS_TRAIN", "false")
+CATEGORY_MAPPING = {"null": 0, "short": 1, "long": 2, "yes": 3, "no": 4}
+
+
+def _get_single_answer(example):
+ def choose_first(answer, is_long_answer=False):
+ assert isinstance(answer, list)
+ if len(answer) == 1:
+ answer = answer[0]
+ return {k: [answer[k]] for k in answer} if is_long_answer else answer
+ for a in answer:
+ if is_long_answer:
+ a = {k: [a[k]] for k in a}
+ if len(a["start_token"]) > 0:
+ break
+ return a
+
+ answer = {"id": example["id"]}
+ annotation = example["annotations"]
+ yes_no_answer = annotation["yes_no_answer"]
+ if 0 in yes_no_answer or 1 in yes_no_answer:
+ answer["category"] = ["yes"] if 1 in yes_no_answer else ["no"]
+ answer["start_token"] = answer["end_token"] = []
+ answer["start_byte"] = answer["end_byte"] = []
+ answer["text"] = [""]
+ else:
+ answer["category"] = ["short"]
+ out = choose_first(annotation["short_answers"])
+ if len(out["start_token"]) == 0:
+ # answer will be long if short is not available
+ answer["category"] = ["long"]
+ out = choose_first(annotation["long_answer"], is_long_answer=True)
+ out["text"] = []
+ answer.update(out)
+
+ # disregard some samples
+ if len(answer["start_token"]) > 1 or answer["start_token"] == answer["end_token"]:
+ answer["remove_it"] = True
+ else:
+ answer["remove_it"] = False
+
+ cols = ["start_token", "end_token", "start_byte", "end_byte", "text"]
+ if not all(isinstance(answer[k], list) for k in cols):
+ raise ValueError("Issue in ID", example["id"])
+
+ return answer
+
+
+def get_context_and_ans(example, assertion=False):
+ """Gives new context after removing & new answer tokens as per new context"""
+ answer = _get_single_answer(example)
+ # bytes are of no use
+ del answer["start_byte"]
+ del answer["end_byte"]
+
+ # handle yes_no answers explicitly
+ if answer["category"][0] in ["yes", "no"]: # category is list with one element
+ doc = example["document"]["tokens"]
+ context = []
+ for i in range(len(doc["token"])):
+ if not doc["is_html"][i]:
+ context.append(doc["token"][i])
+ return {
+ "context": " ".join(context),
+ "answer": {
+ "start_token": -100, # ignore index in cross-entropy
+ "end_token": -100, # ignore index in cross-entropy
+ "category": answer["category"],
+ "span": answer["category"], # extra
+ },
+ }
+
+ # later, help in removing all no answers
+ if answer["start_token"] == [-1]:
+ return {
+ "context": "None",
+ "answer": {
+ "start_token": -1,
+ "end_token": -1,
+ "category": "null",
+ "span": "None", # extra
+ },
+ }
+
+ # handling normal samples
+
+ cols = ["start_token", "end_token"]
+ answer.update({k: answer[k][0] if len(answer[k]) > 0 else answer[k] for k in cols}) # e.g. [10] == 10
+
+ doc = example["document"]["tokens"]
+ start_token = answer["start_token"]
+ end_token = answer["end_token"]
+
+ context = []
+ for i in range(len(doc["token"])):
+ if not doc["is_html"][i]:
+ context.append(doc["token"][i])
+ else:
+ if answer["start_token"] > i:
+ start_token -= 1
+ if answer["end_token"] > i:
+ end_token -= 1
+ new = " ".join(context[start_token:end_token])
+
+ # checking above code
+ if assertion:
+ """checking if above code is working as expected for all the samples"""
+ is_html = doc["is_html"][answer["start_token"] : answer["end_token"]]
+ old = doc["token"][answer["start_token"] : answer["end_token"]]
+ old = " ".join([old[i] for i in range(len(old)) if not is_html[i]])
+ if new != old:
+ print("ID:", example["id"])
+ print("New:", new, end="\n")
+ print("Old:", old, end="\n\n")
+
+ return {
+ "context": " ".join(context),
+ "answer": {
+ "start_token": start_token,
+ "end_token": end_token - 1, # this makes it inclusive
+ "category": answer["category"], # either long or short
+ "span": new, # extra
+ },
+ }
+
+
+def get_strided_contexts_and_ans(example, tokenizer, doc_stride=2048, max_length=4096, assertion=True):
+ # overlap will be of doc_stride - q_len
+
+ out = get_context_and_ans(example, assertion=assertion)
+ answer = out["answer"]
+
+ # later, removing these samples
+ if answer["start_token"] == -1:
+ return {
+ "example_id": example["id"],
+ "input_ids": [[-1]],
+ "labels": {
+ "start_token": [-1],
+ "end_token": [-1],
+ "category": ["null"],
+ },
+ }
+
+ input_ids = tokenizer(example["question"]["text"], out["context"]).input_ids
+ q_len = input_ids.index(tokenizer.sep_token_id) + 1
+
+ # return yes/no
+ if answer["category"][0] in ["yes", "no"]: # category is list with one element
+ inputs = []
+ category = []
+ q_indices = input_ids[:q_len]
+ doc_start_indices = range(q_len, len(input_ids), max_length - doc_stride)
+ for i in doc_start_indices:
+ end_index = i + max_length - q_len
+ slice = input_ids[i:end_index]
+ inputs.append(q_indices + slice)
+ category.append(answer["category"][0])
+ if slice[-1] == tokenizer.sep_token_id:
+ break
+
+ return {
+ "example_id": example["id"],
+ "input_ids": inputs,
+ "labels": {
+ "start_token": [-100] * len(category),
+ "end_token": [-100] * len(category),
+ "category": category,
+ },
+ }
+
+ splitted_context = out["context"].split()
+ complete_end_token = splitted_context[answer["end_token"]]
+ answer["start_token"] = len(
+ tokenizer(
+ " ".join(splitted_context[: answer["start_token"]]),
+ add_special_tokens=False,
+ ).input_ids
+ )
+ answer["end_token"] = len(
+ tokenizer(" ".join(splitted_context[: answer["end_token"]]), add_special_tokens=False).input_ids
+ )
+
+ answer["start_token"] += q_len
+ answer["end_token"] += q_len
+
+ # fixing end token
+ num_sub_tokens = len(tokenizer(complete_end_token, add_special_tokens=False).input_ids)
+ if num_sub_tokens > 1:
+ answer["end_token"] += num_sub_tokens - 1
+
+ old = input_ids[answer["start_token"] : answer["end_token"] + 1] # right & left are inclusive
+ start_token = answer["start_token"]
+ end_token = answer["end_token"]
+
+ if assertion:
+ """This won't match exactly because of extra gaps => visaully inspect everything"""
+ new = tokenizer.decode(old)
+ if answer["span"] != new:
+ print("ISSUE IN TOKENIZATION")
+ print("OLD:", answer["span"])
+ print("NEW:", new, end="\n\n")
+
+ if len(input_ids) <= max_length:
+ return {
+ "example_id": example["id"],
+ "input_ids": [input_ids],
+ "labels": {
+ "start_token": [answer["start_token"]],
+ "end_token": [answer["end_token"]],
+ "category": answer["category"],
+ },
+ }
+
+ q_indices = input_ids[:q_len]
+ doc_start_indices = range(q_len, len(input_ids), max_length - doc_stride)
+
+ inputs = []
+ answers_start_token = []
+ answers_end_token = []
+ answers_category = [] # null, yes, no, long, short
+ for i in doc_start_indices:
+ end_index = i + max_length - q_len
+ slice = input_ids[i:end_index]
+ inputs.append(q_indices + slice)
+ assert len(inputs[-1]) <= max_length, "Issue in truncating length"
+
+ if start_token >= i and end_token <= end_index - 1:
+ start_token = start_token - i + q_len
+ end_token = end_token - i + q_len
+ answers_category.append(answer["category"][0]) # ["short"] -> "short"
+ else:
+ start_token = -100
+ end_token = -100
+ answers_category.append("null")
+ new = inputs[-1][start_token : end_token + 1]
+
+ answers_start_token.append(start_token)
+ answers_end_token.append(end_token)
+ if assertion:
+ """checking if above code is working as expected for all the samples"""
+ if new != old and new != [tokenizer.cls_token_id]:
+ print("ISSUE in strided for ID:", example["id"])
+ print("New:", tokenizer.decode(new))
+ print("Old:", tokenizer.decode(old), end="\n\n")
+ if slice[-1] == tokenizer.sep_token_id:
+ break
+
+ return {
+ "example_id": example["id"],
+ "input_ids": inputs,
+ "labels": {
+ "start_token": answers_start_token,
+ "end_token": answers_end_token,
+ "category": answers_category,
+ },
+ }
+
+
+def prepare_inputs(example, tokenizer, doc_stride=2048, max_length=4096, assertion=False):
+ example = get_strided_contexts_and_ans(
+ example,
+ tokenizer,
+ doc_stride=doc_stride,
+ max_length=max_length,
+ assertion=assertion,
+ )
+
+ return example
+
+
+def save_to_disk(hf_data, file_name):
+ with jsonlines.open(file_name, "a") as writer:
+ for example in tqdm(hf_data, total=len(hf_data), desc="Saving samples ... "):
+ labels = example["labels"]
+ for ids, start, end, cat in zip(
+ example["input_ids"],
+ labels["start_token"],
+ labels["end_token"],
+ labels["category"],
+ ):
+ if start == -1 and end == -1:
+ continue # leave waste samples with no answer
+ if cat == "null" and np.random.rand() < 0.6:
+ continue # removing 50 % samples
+ writer.write(
+ {
+ "input_ids": ids,
+ "start_token": start,
+ "end_token": end,
+ "category": CATEGORY_MAPPING[cat],
+ }
+ )
+
+
+if __name__ == "__main__":
+ """Running area"""
+ from datasets import load_dataset
+
+ from transformers import BigBirdTokenizer
+
+ data = load_dataset("natural_questions")
+ tokenizer = BigBirdTokenizer.from_pretrained("google/bigbird-roberta-base")
+
+ data = data["train" if PROCESS_TRAIN == "true" else "validation"]
+
+ fn_kwargs = {
+ "tokenizer": tokenizer,
+ "doc_stride": DOC_STRIDE,
+ "max_length": MAX_LENGTH,
+ "assertion": False,
+ }
+ data = data.map(prepare_inputs, fn_kwargs=fn_kwargs)
+ data = data.remove_columns(["annotations", "document", "id", "question"])
+ print(data)
+
+ np.random.seed(SEED)
+ cache_file_name = "nq-training.jsonl" if PROCESS_TRAIN == "true" else "nq-validation.jsonl"
+ save_to_disk(data, file_name=cache_file_name)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..b1bc8a7ace24b44fb6805108b4bc11293eab3ed2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/requirements.txt
@@ -0,0 +1,6 @@
+git+https://github.com/huggingface/transformers@main
+datasets
+sentencepiece
+wandb
+flax
+jsonlines
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/sweep_flax.yaml b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/sweep_flax.yaml
new file mode 100644
index 0000000000000000000000000000000000000000..d804f61b3e16f063368c187e3de598dc1094ffe6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/sweep_flax.yaml
@@ -0,0 +1,16 @@
+command:
+ - python3
+ - train.py
+method: random
+parameters:
+ lr:
+ values: [4e-5, 3e-5]
+ warmup_steps:
+ values: [20000, 15000, 10000, 5000]
+ weight_decay:
+ distribution: normal
+ mu: 1e-2
+ sigma: 2e-3
+metric:
+ name: eval_loss
+ goal: minimize
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/train.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/train.py
new file mode 100644
index 0000000000000000000000000000000000000000..ce37b7f975bb3aceb41df88ef1b51bfe71098408
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/big_bird/train.py
@@ -0,0 +1,78 @@
+import os
+from dataclasses import replace
+
+import jax
+import wandb
+from bigbird_flax import Args, DataCollator, FlaxBigBirdForNaturalQuestions, Trainer, build_tx, train_step, val_step
+from datasets import load_dataset
+from flax import jax_utils
+
+from transformers import BigBirdTokenizerFast
+
+
+if __name__ == "__main__":
+ print("#################### AVAILABLE DEVICES ####################")
+ print(jax.devices())
+ print("###########################################################")
+
+ # setup for wandb sweep
+ args = Args()
+ logger = wandb.init(project="bigbird-natural-questions", config=args.__dict__)
+ wandb_args = dict(logger.config)
+ del wandb_args["batch_size"]
+ args = replace(args, **wandb_args)
+ base_dir = args.base_dir + "-" + wandb.run.id
+ args = replace(args, base_dir=base_dir)
+ print(args)
+
+ tr_dataset = load_dataset("json", data_files=args.tr_data_path)["train"]
+ val_dataset = load_dataset("json", data_files=args.val_data_path)["train"]
+
+ # drop extra batch for now
+ indices = range(len(tr_dataset) - len(tr_dataset) % args.batch_size)
+ tr_dataset = tr_dataset.shuffle().select(indices)
+ indices = range(len(val_dataset) - len(val_dataset) % args.batch_size)
+ val_dataset = val_dataset.shuffle().select(indices)
+
+ if os.environ.get("TRAIN_ON_SMALL", "false") == "true":
+ tr_dataset = tr_dataset.shuffle().select(range(80000))
+ val_dataset = val_dataset.shuffle().select(range(8000))
+
+ print(tr_dataset)
+ print(val_dataset)
+
+ model = FlaxBigBirdForNaturalQuestions.from_pretrained(
+ args.model_id, block_size=args.block_size, num_random_blocks=args.num_random_blocks
+ )
+ tokenizer = BigBirdTokenizerFast.from_pretrained(args.model_id)
+ data_collator = DataCollator(pad_id=tokenizer.pad_token_id, max_length=4096)
+
+ tx_args = {
+ "lr": args.lr,
+ "init_lr": args.init_lr,
+ "warmup_steps": args.warmup_steps,
+ "num_train_steps": args.max_epochs * (len(tr_dataset) // args.batch_size),
+ "weight_decay": args.weight_decay,
+ }
+ tx, lr = build_tx(**tx_args)
+
+ trainer = Trainer(
+ args=args,
+ data_collator=data_collator,
+ model_save_fn=model.save_pretrained,
+ train_step_fn=train_step,
+ val_step_fn=val_step,
+ logger=logger,
+ scheduler_fn=lr,
+ )
+
+ ckpt_dir = None
+ state = trainer.create_state(model, tx, num_train_steps=tx_args["num_train_steps"], ckpt_dir=ckpt_dir)
+ try:
+ trainer.train(state, tr_dataset, val_dataset)
+ except KeyboardInterrupt:
+ print("Oooops; TRAINING STOPPED UNFORTUNATELY")
+
+ print("SAVING WEIGHTS IN `final-weights`")
+ params = jax_utils.unreplicate(state.params)
+ model.save_pretrained(os.path.join(args.base_dir, "final-weights"), params=params)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/dataset-streaming/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/dataset-streaming/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..bdb6629e509c6fa7f5a6987a9a184fe581af4cd0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/dataset-streaming/README.md
@@ -0,0 +1,121 @@
+
+
+# Language model training examples in streaming mode
+
+The following examples showcase how to train a language model from scratch
+using the JAX/Flax backend.
+
+JAX/Flax allows you to trace pure functions and compile them into efficient, fused accelerator code on both GPU and TPU.
+Models written in JAX/Flax are **immutable** and updated in a purely functional
+way which enables simple and efficient model parallelism.
+
+All of the following examples make use of [dataset streaming](https://huggingface.co/docs/datasets/master/dataset_streaming), therefore allowing to train models on massive datasets\
+without ever having to download the full dataset.
+
+## Masked language modeling
+
+In the following, we demonstrate how to train a bi-directional transformer model
+using masked language modeling objective as introduced in [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805).
+More specifically, we demonstrate how JAX/Flax and dataset streaming can be leveraged
+to pre-train [**`FacebookAI/roberta-base`**](https://huggingface.co/FacebookAI/roberta-base)
+in English on a single TPUv3-8 pod for 10000 update steps.
+
+The example script uses the 🤗 Datasets library. You can easily customize them to your needs if you need extra processing on your datasets.
+
+Let's start by creating a model repository to save the trained model and logs.
+Here we call the model `"english-roberta-base-dummy"`, but you can change the model name as you like.
+
+You can do this either directly on [huggingface.co](https://huggingface.co/new) (assuming that
+you are logged in) or via the command line:
+
+```bash
+huggingface-cli repo create english-roberta-base-dummy
+```
+
+Next we clone the model repository to add the tokenizer and model files.
+
+```bash
+git clone https://huggingface.co//english-roberta-base-dummy
+```
+
+To ensure that all tensorboard traces will be uploaded correctly, we need to
+track them. You can run the following command inside your model repo to do so.
+
+```bash
+cd english-roberta-base-dummy
+git lfs track "*tfevents*"
+```
+
+Great, we have set up our model repository. During training, we will automatically
+push the training logs and model weights to the repo.
+
+Next, let's add a symbolic link to the `run_mlm_flax.py`.
+
+```bash
+export MODEL_DIR="./english-roberta-base-dummy"
+ln -s ~/transformers/examples/research_projects/jax-projects/dataset-streaming/run_mlm_flax_stream.py ./
+```
+
+### Copy config and tokenizer of existing model
+
+In this example, we will simply copy an existing config and tokenizer in English.
+You can run the following code in a Python shell to do so.
+
+```python
+from transformers import RobertaTokenizerFast, RobertaConfig
+
+model_dir = "./english-roberta-base-dummy"
+
+tokenizer = RobertaTokenizerFast.from_pretrained("FacebookAI/roberta-base")
+config = RobertaConfig.from_pretrained("FacebookAI/roberta-base")
+
+tokenizer.save_pretrained(model_dir)
+config.save_pretrained(model_dir)
+```
+
+### Train model
+
+Next we can run the example script to pretrain the model.
+Compared to the default [`run_mlm_flax`](https://github.com/huggingface/transformers/blob/main/examples/flax/language-modeling/run_mlm_flax.py), we introduced 4 new training settings:
+- `num_train_steps` - how many update steps should be run.
+- `num_eval_samples` - how many training samples should be taken for evaluation.
+- `logging_steps` - at what rate should the training loss be logged.
+- `eval_steps` - at what rate should evaluation be run.
+10K update steps
+
+```bash
+./run_mlm_flax_stream.py \
+ --output_dir="${MODEL_DIR}" \
+ --model_type="roberta" \
+ --config_name="${MODEL_DIR}" \
+ --tokenizer_name="${MODEL_DIR}" \
+ --dataset_name="oscar" \
+ --dataset_config_name="unshuffled_deduplicated_en" \
+ --max_seq_length="128" \
+ --per_device_train_batch_size="128" \
+ --per_device_eval_batch_size="128" \
+ --learning_rate="3e-4" \
+ --warmup_steps="1000" \
+ --overwrite_output_dir \
+ --adam_beta1="0.9" \
+ --adam_beta2="0.98" \
+ --num_train_steps="10000" \
+ --num_eval_samples="5000" \
+ --logging_steps="250" \
+ --eval_steps="1000" \
+ --push_to_hub
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/dataset-streaming/run_mlm_flax_stream.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/dataset-streaming/run_mlm_flax_stream.py
new file mode 100644
index 0000000000000000000000000000000000000000..8940fab5bda34b6652eac43e13cca849a3c517da
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/dataset-streaming/run_mlm_flax_stream.py
@@ -0,0 +1,637 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Fine-tuning the library models for masked language modeling (BERT, ALBERT, RoBERTa...) with whole word masking on a
+text file or a dataset.
+
+Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
+https://huggingface.co/models?filter=fill-mask
+"""
+
+import logging
+import os
+import sys
+import time
+from collections import defaultdict
+from dataclasses import dataclass, field
+
+# You can also adapt this script on your own masked language modeling task. Pointers for this are left as comments.
+from pathlib import Path
+from typing import Dict, List, Optional, Tuple
+
+import datasets
+import flax
+import jax
+import jax.numpy as jnp
+import numpy as np
+import optax
+from datasets import load_dataset
+from flax import jax_utils, traverse_util
+from flax.training import train_state
+from flax.training.common_utils import get_metrics, onehot, shard
+from tqdm import tqdm
+
+from transformers import (
+ CONFIG_MAPPING,
+ FLAX_MODEL_FOR_MASKED_LM_MAPPING,
+ AutoConfig,
+ AutoTokenizer,
+ FlaxAutoModelForMaskedLM,
+ HfArgumentParser,
+ PreTrainedTokenizerBase,
+ TensorType,
+ TrainingArguments,
+ is_tensorboard_available,
+ set_seed,
+)
+
+
+if datasets.__version__ <= "1.8.0":
+ raise ValueError("Make sure to upgrade `datasets` to a version >= 1.9.0 to use dataset streaming")
+
+
+MODEL_CONFIG_CLASSES = list(FLAX_MODEL_FOR_MASKED_LM_MAPPING.keys())
+MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ model_name_or_path: Optional[str] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
+ )
+ },
+ )
+ model_type: Optional[str] = field(
+ default=None,
+ metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ dtype: Optional[str] = field(
+ default="float32",
+ metadata={
+ "help": (
+ "Floating-point format in which the model weights should be initialized and trained. Choose one of"
+ " `[float32, float16, bfloat16]`."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ dataset_name: Optional[str] = field(
+ default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
+ )
+ dataset_config_name: Optional[str] = field(
+ default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
+ )
+ train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
+ )
+ train_ref_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input train ref data file for whole word masking in Chinese."},
+ )
+ validation_ref_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input validation ref data file for whole word masking in Chinese."},
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ validation_split_percentage: Optional[int] = field(
+ default=5,
+ metadata={
+ "help": "The percentage of the train set used as validation set in case there's no validation split"
+ },
+ )
+ max_seq_length: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated. Default to the max input length of the model."
+ )
+ },
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+ mlm_probability: float = field(
+ default=0.15, metadata={"help": "Ratio of tokens to mask for masked language modeling loss"}
+ )
+ pad_to_max_length: bool = field(
+ default=False,
+ metadata={
+ "help": (
+ "Whether to pad all samples to `max_seq_length`. "
+ "If False, will pad the samples dynamically when batching to the maximum length in the batch."
+ )
+ },
+ )
+ line_by_line: bool = field(
+ default=False,
+ metadata={"help": "Whether distinct lines of text in the dataset are to be handled as distinct sequences."},
+ )
+ text_column_name: str = field(
+ default="text", metadata={"help": "The name of the column to retrieve the training text."}
+ )
+ shuffle_buffer_size: int = field(
+ default=10000, metadata={"help": "The number of examples to pre-load for shuffling."}
+ )
+ num_train_steps: int = field(default=50000, metadata={"help": "The number of training steps."})
+ num_eval_samples: int = field(default=50000, metadata={"help": "The number of samples to be used for evaluation"})
+
+ def __post_init__(self):
+ if self.dataset_name is None and self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, a json or a txt file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, a json or a txt file."
+
+
+@flax.struct.dataclass
+class FlaxDataCollatorForLanguageModeling:
+ """
+ Data collator used for language modeling. Inputs are dynamically padded to the maximum length of a batch if they
+ are not all of the same length.
+
+ Args:
+ tokenizer (:class:`~transformers.PreTrainedTokenizer` or :class:`~transformers.PreTrainedTokenizerFast`):
+ The tokenizer used for encoding the data.
+ mlm_probability (:obj:`float`, `optional`, defaults to 0.15):
+ The probability with which to (randomly) mask tokens in the input.
+
+ .. note::
+
+ For best performance, this data collator should be used with a dataset having items that are dictionaries or
+ BatchEncoding, with the :obj:`"special_tokens_mask"` key, as returned by a
+ :class:`~transformers.PreTrainedTokenizer` or a :class:`~transformers.PreTrainedTokenizerFast` with the
+ argument :obj:`return_special_tokens_mask=True`.
+ """
+
+ tokenizer: PreTrainedTokenizerBase
+ mlm_probability: float = 0.15
+
+ def __post_init__(self):
+ if self.tokenizer.mask_token is None:
+ raise ValueError(
+ "This tokenizer does not have a mask token which is necessary for masked language modeling. "
+ "You should pass `mlm=False` to train on causal language modeling instead."
+ )
+
+ def __call__(self, examples: List[Dict[str, np.ndarray]]) -> Dict[str, np.ndarray]:
+ # Handle dict or lists with proper padding and conversion to tensor.
+ batch = self.tokenizer.pad(examples, return_tensors=TensorType.NUMPY)
+
+ # If special token mask has been preprocessed, pop it from the dict.
+ special_tokens_mask = batch.pop("special_tokens_mask", None)
+
+ batch["input_ids"], batch["labels"] = self.mask_tokens(
+ batch["input_ids"], special_tokens_mask=special_tokens_mask
+ )
+ return batch
+
+ def mask_tokens(
+ self, inputs: np.ndarray, special_tokens_mask: Optional[np.ndarray]
+ ) -> Tuple[jnp.ndarray, jnp.ndarray]:
+ """
+ Prepare masked tokens inputs/labels for masked language modeling: 80% MASK, 10% random, 10% original.
+ """
+ labels = inputs.copy()
+ # We sample a few tokens in each sequence for MLM training (with probability `self.mlm_probability`)
+ probability_matrix = np.full(labels.shape, self.mlm_probability)
+ special_tokens_mask = special_tokens_mask.astype("bool")
+
+ probability_matrix[special_tokens_mask] = 0.0
+ masked_indices = np.random.binomial(1, probability_matrix).astype("bool")
+ labels[~masked_indices] = -100 # We only compute loss on masked tokens
+
+ # 80% of the time, we replace masked input tokens with tokenizer.mask_token ([MASK])
+ indices_replaced = np.random.binomial(1, np.full(labels.shape, 0.8)).astype("bool") & masked_indices
+ inputs[indices_replaced] = self.tokenizer.convert_tokens_to_ids(self.tokenizer.mask_token)
+
+ # 10% of the time, we replace masked input tokens with random word
+ indices_random = np.random.binomial(1, np.full(labels.shape, 0.5)).astype("bool")
+ indices_random &= masked_indices & ~indices_replaced
+
+ random_words = np.random.randint(self.tokenizer.vocab_size, size=labels.shape, dtype="i4")
+ inputs[indices_random] = random_words[indices_random]
+
+ # The rest of the time (10% of the time) we keep the masked input tokens unchanged
+ return inputs, labels
+
+
+def generate_batch_splits(samples_idx: np.ndarray, batch_size: int) -> np.ndarray:
+ num_samples = len(samples_idx)
+ samples_to_remove = num_samples % batch_size
+
+ if samples_to_remove != 0:
+ samples_idx = samples_idx[:-samples_to_remove]
+ sections_split = num_samples // batch_size
+ batch_idx = np.split(samples_idx, sections_split)
+ return batch_idx
+
+
+def advance_iter_and_group_samples(train_iterator, num_samples, max_seq_length):
+ """
+ The training iterator is advanced so that after groupifying the samples,
+ `num_samples` of length `max_seq_length` are returned.
+ """
+ num_total_tokens = max_seq_length * num_samples
+ samples = defaultdict(list)
+
+ i = 0
+ while i < num_total_tokens:
+ tokenized_samples = next(train_iterator)
+ i += len(tokenized_samples["input_ids"])
+
+ # concatenate tokenized samples to list (excluding "id" and "text")
+ samples = {
+ k: samples[k] + tokenized_samples[k] for k in ["input_ids", "attention_mask", "special_tokens_mask"]
+ }
+
+ # Concatenated tokens are split to lists of length `max_seq_length`.
+ # Note that remainedr of % max_seq_length are thrown away.
+ def group_texts(examples):
+ result = {
+ k: [t[i : i + max_seq_length] for i in range(0, num_total_tokens, max_seq_length)]
+ for k, t in examples.items()
+ }
+ return result
+
+ grouped_samples = group_texts(samples)
+ return grouped_samples
+
+
+def write_train_metric(summary_writer, train_metrics, train_time, step):
+ summary_writer.scalar("train_time", train_time, step)
+
+ train_metrics = get_metrics(train_metrics)
+ for key, vals in train_metrics.items():
+ tag = f"train_{key}"
+ for i, val in enumerate(vals):
+ summary_writer.scalar(tag, val, step - len(vals) + i + 1)
+
+
+def write_eval_metric(summary_writer, eval_metrics, step):
+ for metric_name, value in eval_metrics.items():
+ summary_writer.scalar(f"eval_{metric_name}", value, step)
+
+
+if __name__ == "__main__":
+ # See all possible arguments in src/transformers/training_args.py
+ # or by passing the --help flag to this script.
+ # We now keep distinct sets of args, for a cleaner separation of concerns.
+
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ if (
+ os.path.exists(training_args.output_dir)
+ and os.listdir(training_args.output_dir)
+ and training_args.do_train
+ and not training_args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+
+ # Setup logging
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ level="INFO",
+ datefmt="[%X]",
+ )
+
+ # Log on each process the small summary:
+ logger = logging.getLogger(__name__)
+ logger.warning(
+ f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}"
+ + f"distributed training: {bool(training_args.local_rank != -1)}, 16-bits training: {training_args.fp16}"
+ )
+
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ # Set seed before initializing model.
+ set_seed(training_args.seed)
+
+ # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
+ # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
+ # (the dataset will be downloaded automatically from the datasets Hub).
+ #
+ # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
+ # 'text' is found. You can easily tweak this behavior (see below).
+ if data_args.dataset_name is not None:
+ # Downloading and loading a dataset from the hub.
+ dataset = load_dataset(
+ data_args.dataset_name,
+ data_args.dataset_config_name,
+ cache_dir=model_args.cache_dir,
+ streaming=True,
+ split="train",
+ )
+
+ if model_args.config_name:
+ config = AutoConfig.from_pretrained(model_args.config_name, cache_dir=model_args.cache_dir)
+ elif model_args.model_name_or_path:
+ config = AutoConfig.from_pretrained(model_args.model_name_or_path, cache_dir=model_args.cache_dir)
+ else:
+ config = CONFIG_MAPPING[model_args.model_type]()
+ logger.warning("You are instantiating a new config instance from scratch.")
+
+ if model_args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name, cache_dir=model_args.cache_dir, use_fast=model_args.use_fast_tokenizer
+ )
+ elif model_args.model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.model_name_or_path, cache_dir=model_args.cache_dir, use_fast=model_args.use_fast_tokenizer
+ )
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ # Otherwise, we tokenize every text, then concatenate them together before splitting them in smaller parts.
+ # We use `return_special_tokens_mask=True` because DataCollatorForLanguageModeling (see below) is more
+ # efficient when it receives the `special_tokens_mask`.
+ def tokenize_function(examples):
+ return tokenizer(examples[data_args.text_column_name], return_special_tokens_mask=True)
+
+ tokenized_datasets = dataset.map(tokenize_function, batched=True, remove_columns=list(dataset.features.keys()))
+
+ shuffle_seed = training_args.seed
+ tokenized_datasets = tokenized_datasets.shuffle(buffer_size=data_args.shuffle_buffer_size, seed=shuffle_seed)
+
+ has_tensorboard = is_tensorboard_available()
+ if has_tensorboard and jax.process_index() == 0:
+ try:
+ from flax.metrics.tensorboard import SummaryWriter
+ except ImportError as ie:
+ has_tensorboard = False
+ logger.warning(
+ f"Unable to display metrics through TensorBoard because some package are not installed: {ie}"
+ )
+
+ summary_writer = SummaryWriter(log_dir=Path(training_args.output_dir))
+
+ # Data collator
+ # This one will take care of randomly masking the tokens.
+ data_collator = FlaxDataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=data_args.mlm_probability)
+
+ # Initialize our training
+ rng = jax.random.PRNGKey(training_args.seed)
+ dropout_rngs = jax.random.split(rng, jax.local_device_count())
+
+ if model_args.model_name_or_path:
+ model = FlaxAutoModelForMaskedLM.from_pretrained(
+ model_args.model_name_or_path, config=config, seed=training_args.seed, dtype=getattr(jnp, model_args.dtype)
+ )
+ else:
+ model = FlaxAutoModelForMaskedLM.from_config(
+ config, seed=training_args.seed, dtype=getattr(jnp, model_args.dtype)
+ )
+
+ # Store some constant
+ num_epochs = int(training_args.num_train_epochs)
+ train_batch_size = int(training_args.per_device_train_batch_size) * jax.device_count()
+ eval_batch_size = int(training_args.per_device_eval_batch_size) * jax.device_count()
+
+ # define number steps per stream epoch
+ num_train_steps = data_args.num_train_steps
+
+ # Create learning rate schedule
+ warmup_fn = optax.linear_schedule(
+ init_value=0.0, end_value=training_args.learning_rate, transition_steps=training_args.warmup_steps
+ )
+ decay_fn = optax.linear_schedule(
+ init_value=training_args.learning_rate,
+ end_value=0,
+ transition_steps=num_train_steps - training_args.warmup_steps,
+ )
+ linear_decay_lr_schedule_fn = optax.join_schedules(
+ schedules=[warmup_fn, decay_fn], boundaries=[training_args.warmup_steps]
+ )
+
+ # We use Optax's "masking" functionality to not apply weight decay
+ # to bias and LayerNorm scale parameters. decay_mask_fn returns a
+ # mask boolean with the same structure as the parameters.
+ # The mask is True for parameters that should be decayed.
+ # Note that this mask is specifically adapted for FlaxBERT-like models.
+ # For other models, one should correct the layer norm parameter naming
+ # accordingly.
+ def decay_mask_fn(params):
+ flat_params = traverse_util.flatten_dict(params)
+ flat_mask = {path: (path[-1] != "bias" and path[-2:] != ("LayerNorm", "scale")) for path in flat_params}
+ return traverse_util.unflatten_dict(flat_mask)
+
+ # create adam optimizer
+ adamw = optax.adamw(
+ learning_rate=linear_decay_lr_schedule_fn,
+ b1=training_args.adam_beta1,
+ b2=training_args.adam_beta2,
+ eps=training_args.adam_epsilon,
+ weight_decay=training_args.weight_decay,
+ mask=decay_mask_fn,
+ )
+
+ # Setup train state
+ state = train_state.TrainState.create(apply_fn=model.__call__, params=model.params, tx=adamw)
+
+ # Define gradient update step fn
+ def train_step(state, batch, dropout_rng):
+ dropout_rng, new_dropout_rng = jax.random.split(dropout_rng)
+
+ def loss_fn(params):
+ labels = batch.pop("labels")
+
+ logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
+
+ # compute loss, ignore padded input tokens
+ label_mask = jnp.where(labels > 0, 1.0, 0.0)
+ loss = optax.softmax_cross_entropy(logits, onehot(labels, logits.shape[-1])) * label_mask
+
+ # take average
+ loss = loss.sum() / label_mask.sum()
+
+ return loss
+
+ grad_fn = jax.value_and_grad(loss_fn)
+ loss, grad = grad_fn(state.params)
+ grad = jax.lax.pmean(grad, "batch")
+ new_state = state.apply_gradients(grads=grad)
+
+ metrics = jax.lax.pmean(
+ {"loss": loss, "learning_rate": linear_decay_lr_schedule_fn(state.step)}, axis_name="batch"
+ )
+
+ return new_state, metrics, new_dropout_rng
+
+ # Create parallel version of the train step
+ p_train_step = jax.pmap(train_step, "batch", donate_argnums=(0,))
+
+ # Define eval fn
+ def eval_step(params, batch):
+ labels = batch.pop("labels")
+
+ logits = model(**batch, params=params, train=False)[0]
+
+ # compute loss, ignore padded input tokens
+ label_mask = jnp.where(labels > 0, 1.0, 0.0)
+ loss = optax.softmax_cross_entropy(logits, onehot(labels, logits.shape[-1])) * label_mask
+
+ # compute accuracy
+ accuracy = jnp.equal(jnp.argmax(logits, axis=-1), labels) * label_mask
+
+ # summarize metrics
+ metrics = {"loss": loss.sum(), "accuracy": accuracy.sum(), "normalizer": label_mask.sum()}
+ metrics = jax.lax.psum(metrics, axis_name="batch")
+
+ return metrics
+
+ p_eval_step = jax.pmap(eval_step, "batch", donate_argnums=(0,))
+
+ # Replicate the train state on each device
+ state = jax_utils.replicate(state)
+
+ train_time = 0
+ train_start = time.time()
+ train_metrics = []
+ eval_metrics = []
+
+ training_iter = iter(tokenized_datasets)
+
+ max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
+ eval_samples = advance_iter_and_group_samples(training_iter, data_args.num_eval_samples, max_seq_length)
+
+ steps = tqdm(range(num_train_steps), desc="Training...", position=0)
+ for step in range(num_train_steps):
+ # ======================== Training ================================
+ try:
+ samples = advance_iter_and_group_samples(training_iter, train_batch_size, max_seq_length)
+ except StopIteration:
+ # Once the end of the dataset stream is reached, the training iterator
+ # is reinitialized and reshuffled and a new eval dataset is randomly chosen.
+ shuffle_seed += 1
+ tokenized_datasets.set_epoch(shuffle_seed)
+
+ training_iter = iter(tokenized_datasets)
+
+ eval_dataset = advance_iter_and_group_samples(training_iter, data_args.num_eval_samples, max_seq_length)
+ samples = advance_iter_and_group_samples(training_iter, train_batch_size, max_seq_length)
+
+ # process input samples
+ model_inputs = data_collator(samples)
+
+ # Model forward
+ model_inputs = shard(model_inputs.data)
+ state, train_metric, dropout_rngs = p_train_step(state, model_inputs, dropout_rngs)
+
+ train_metrics.append(train_metric)
+
+ if step % training_args.logging_steps == 0 and step > 0:
+ steps.write(
+ f"Step... ({step} | Loss: {train_metric['loss'].mean()}, Learning Rate:"
+ f" {train_metric['learning_rate'].mean()})"
+ )
+ train_time += time.time() - train_start
+ if has_tensorboard and jax.process_index() == 0:
+ write_train_metric(summary_writer, train_metrics, train_time, step)
+ train_metrics = []
+
+ # ======================== Evaluating ==============================
+ if step % training_args.eval_steps == 0 and step > 0:
+ # Avoid using jax.numpy here in case of TPU training
+ eval_samples_idx = np.arange(data_args.num_eval_samples)
+ eval_batch_idx = generate_batch_splits(eval_samples_idx, eval_batch_size)
+
+ for i, batch_idx in enumerate(tqdm(eval_batch_idx, desc="Evaluating ...", position=1)):
+ # process input samples
+ batch_eval_samples = {k: [v[idx] for idx in batch_idx] for k, v in eval_samples.items()}
+ model_inputs = data_collator(batch_eval_samples)
+
+ # Model forward
+ model_inputs = shard(model_inputs.data)
+ metrics = p_eval_step(state.params, model_inputs)
+ eval_metrics.append(metrics)
+
+ # normalize eval metrics
+ eval_metrics = get_metrics(eval_metrics)
+ eval_metrics = jax.tree_util.tree_map(jnp.sum, eval_metrics)
+ eval_normalizer = eval_metrics.pop("normalizer")
+ eval_metrics = jax.tree_util.tree_map(lambda x: x / eval_normalizer, eval_metrics)
+
+ # Update progress bar
+ steps.desc = (
+ f"Step... ({step + 1}/{num_train_steps} | Loss: {eval_metrics['loss']}, Acc:"
+ f" {eval_metrics['accuracy']})"
+ )
+
+ if has_tensorboard and jax.process_index() == 0:
+ write_eval_metric(summary_writer, eval_metrics, step)
+ eval_metrics = []
+
+ # save checkpoint after each epoch and push checkpoint to the hub
+ if jax.process_index() == 0:
+ params = jax.device_get(jax.tree_util.tree_map(lambda x: x[0], state.params))
+ model.save_pretrained(
+ training_args.output_dir,
+ params=params,
+ push_to_hub=training_args.push_to_hub,
+ commit_message=f"Saving weights and logs of step {step+1}",
+ )
+
+ # update tqdm bar
+ steps.update(1)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/hybrid_clip/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/hybrid_clip/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..72d3db1935895f4c53732e0c8dd554a8ca0840e5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/hybrid_clip/README.md
@@ -0,0 +1,172 @@
+
+
+# Vision-Text dual encoder model training examples
+
+> Note: This example is experimental and might not give the best possible results
+
+The following example showcases how to train a CLIP like vision-text dual encoder model
+using a pre-trained vision and text encoder using the JAX/Flax backend.
+
+Such a model can be used for natural language image search and potentially zero-shot image classification.
+The model is inspired by the [CLIP](https://openai.com/blog/clip/) approach, introduced by Alec Radford et al.
+The idea is to train a vision encoder and a text encoder jointly to project the representation of images and their
+captions into the same embedding space, such that the caption embeddings are located near the embeddings
+of the images they describe.
+
+JAX/Flax allows you to trace pure functions and compile them into efficient, fused accelerator code on both GPU and TPU.
+Models written in JAX/Flax are **immutable** and updated in a purely functional
+way which enables simple and efficient model parallelism.
+
+In this example we will use the vision model from [CLIP](https://huggingface.co/models?filter=clip)
+as the image encoder and [`FacebookAI/roberta-base`](https://huggingface.co/FacebookAI/roberta-base) as the text encoder.
+Note that one can also use the [ViT](https://huggingface.co/models?filter=vit) model as image encoder and any other BERT or ROBERTa model as text encoder.
+To train the model on languages other than English one should choose a text encoder trained on the desired
+language and a image-text dataset in that language. One such dataset is [WIT](https://github.com/google-research-datasets/wit).
+
+Let's start by creating a model repository to save the trained model and logs.
+Here we call the model `"clip-roberta-base"`, but you can change the model name as you like.
+
+You can do this either directly on [huggingface.co](https://huggingface.co/new) (assuming that
+you are logged in) or via the command line:
+
+```bash
+huggingface-cli repo create clip-roberta-base
+```
+Next we clone the model repository to add the tokenizer and model files.
+```bash
+git clone https://huggingface.co//clip-roberta-base
+```
+To ensure that all tensorboard traces will be uploaded correctly, we need to
+track them. You can run the following command inside your model repo to do so.
+
+```bash
+cd clip-roberta-base
+git lfs track "*tfevents*"
+```
+
+Great, we have set up our model repository. During training, we will automatically
+push the training logs and model weights to the repo.
+
+Next, let's add a symbolic link to the `run_hybrid_clip.py`.
+
+```bash
+export MODEL_DIR="./clip-roberta-base
+ln -s ~/transformers/examples/research_projects/jax-projects/hybrid_clip/run_hybrid_clip.py run_hybrid_clip.py
+```
+
+## How to use the `FlaxHybridCLIP` model:
+
+The `FlaxHybridCLIP` class let's you load any text and vision encoder model to create a dual encoder.
+Here is an example of how to load the model using pre-trained text and vision models.
+
+```python
+from modeling_hybrid_clip import FlaxHybridCLIP
+
+model = FlaxHybridCLIP.from_text_vision_pretrained("google-bert/bert-base-uncased", "openai/clip-vit-base-patch32")
+
+# save the model
+model.save_pretrained("bert-clip")
+
+# load the saved model
+model = FlaxHybridCLIP.from_pretrained("bert-clip")
+```
+
+If the checkpoints are in PyTorch then one could pass `text_from_pt=True` and `vision_from_pt=True`. This will load the model
+PyTorch checkpoints convert them to flax and load the model.
+
+```python
+model = FlaxHybridCLIP.from_text_vision_pretrained("google-bert/bert-base-uncased", "openai/clip-vit-base-patch32", text_from_pt=True, vision_from_pt=True)
+```
+
+This loads both the text and vision encoders using pre-trained weights, the projection layers are randomly
+initialized except for CLIP's vision model. If you use CLIP to initialize the vision model then the vision projection weights are also
+loaded using the pre-trained weights.
+
+## Prepare the dataset
+
+We will use the MS-COCO dataset to train our dual encoder model. MS-COCO contains over 82,000 images, each of which has at least 5 different caption annotations. The dataset is usually used for image captioning tasks, but we can repurpose the image-caption pairs to train our dual encoder model for image search.
+
+### Download and extract the data.
+
+It consists of two compressed folders: one with images, and the other—with associated image captions. Note that the compressed images folder is 13GB in size.
+
+```bash
+wget http://images.cocodataset.org/annotations/annotations_trainval2014.zip
+wget http://images.cocodataset.org/zips/train2014.zip
+
+unzip annotations_trainval2014.zip
+unzip train2014.zip
+
+mkdir coco_dataset
+mv train2014 coco_dataset/
+mv annotations coco_dataset/
+```
+
+### Prepare dataset files and split the dataset.
+
+```python
+import json
+import collections
+
+images_dir = "coco_dataset/train2014"
+annotation_file = "coco_dataset/annotations/captions_train2014.json"
+with open(annotation_file, "r") as f:
+ annotations = json.load(f)["annotations"]
+
+image_path_to_caption = collections.defaultdict(list)
+for element in annotations:
+ caption = f"{element['caption'].lower().rstrip('.')}"
+ image_path = images_dir + "/COCO_train2014_" + "%012d.jpg" % (element["image_id"])
+ image_path_to_caption[image_path].append(caption)
+
+lines = []
+for image_path, captions in image_path_to_caption.items():
+ lines.append(json.dumps({"image_path": image_path, "captions": captions}))
+
+train_lines = lines[:-8000]
+valid_line = lines[-8000:]
+with open("coco_dataset/train_dataset.json", "w") as f:
+ f.write("\n".join(train_lines))
+
+with open("coco_dataset/valid_dataset.json", "w") as f:
+ f.write("\n".join(valid_line))
+```
+
+> Note: The data loading and processing part of this script can still be improved for maximum performance. In particular one should decode the images beforehand and use those instead decoding them each time. If the dataset is small or if you have huge disk space the you could also pre-process all the dataset beforehand and then use it.
+
+## Train the model
+Next we can run the example script to train the model:
+
+```bash
+python run_hybrid_clip.py \
+ --output_dir ${MODEL_DIR} \
+ --text_model_name_or_path="FacebookAI/roberta-base" \
+ --vision_model_name_or_path="openai/clip-vit-base-patch32" \
+ --tokenizer_name="FacebookAI/roberta-base" \
+ --train_file="coco_dataset/train_dataset.json" \
+ --validation_file="coco_dataset/validation_dataset.json" \
+ --do_train --do_eval \
+ --num_train_epochs="40" --max_seq_length 96 \
+ --per_device_train_batch_size="64" \
+ --per_device_eval_batch_size="64" \
+ --learning_rate="5e-5" --warmup_steps="0" --weight_decay 0.1 \
+ --overwrite_output_dir \
+ --preprocessing_num_workers 32 \
+ --push_to_hub
+```
+
+This should finish in ~1h50 mins with min validation loss 2.43. Training statistics can be accessed on [tfhub.de](https://tensorboard.dev/experiment/RUNPYd1yRgSD5kZSb9hDig/#scalars)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/hybrid_clip/configuration_hybrid_clip.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/hybrid_clip/configuration_hybrid_clip.py
new file mode 100644
index 0000000000000000000000000000000000000000..5272ac44a1a884eaf9b058c9e29729bfaec29a58
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/hybrid_clip/configuration_hybrid_clip.py
@@ -0,0 +1,112 @@
+import copy
+
+from transformers.configuration_utils import PretrainedConfig
+from transformers.utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class HybridCLIPConfig(PretrainedConfig):
+ r"""
+ :class:`HybridCLIPConfig` is the configuration class to store the configuration of a
+ :class:`~HybridCLIPModel`. It is used to instantiate HybridCLIPModel model according to the specified arguments,
+ defining the text model and vision model configs.
+
+ Configuration objects inherit from :class:`~transformers.PretrainedConfig` and can be used to control the model
+ outputs. Read the documentation from :class:`~transformers.PretrainedConfig` for more information.
+
+ Args:
+ text_config_dict (:obj:`dict`):
+ Dictionary of configuration options that defines text model config.
+ vision_config_dict (:obj:`dict`):
+ Dictionary of configuration options that defines vison model config.
+ projection_dim (:obj:`int`, `optional`, defaults to 512):
+ Dimentionality of text and vision projection layers.
+ kwargs (`optional`):
+ Dictionary of keyword arguments.
+
+ Examples::
+
+ >>> from transformers import BertConfig, CLIPConfig, HybridCLIPConfig, FlaxHybridCLIP
+
+ >>> # Initializing a BERT and CLIP configuration
+ >>> config_text = BertConfig()
+ >>> config_vision = CLIPConfig()
+
+ >>> config = HybridCLIPConfig.from_text_vision_configs(config_text, config_vision, projection_dim=512)
+
+ >>> # Initializing a BERT and CLIPVision model
+ >>> model = EncoderDecoderModel(config=config)
+
+ >>> # Accessing the model configuration
+ >>> config_text = model.config.text_config
+ >>> config_vision = model.config.vision_config
+
+ >>> # Saving the model, including its configuration
+ >>> model.save_pretrained('my-model')
+
+ >>> # loading model and config from pretrained folder
+ >>> encoder_decoder_config = HybridCLIPConfig.from_pretrained('my-model')
+ >>> model = FlaxHybridCLIP.from_pretrained('my-model', config=encoder_decoder_config)
+ """
+
+ model_type = "hybrid-clip"
+ is_composition = True
+
+ def __init__(self, projection_dim=512, **kwargs):
+ super().__init__(**kwargs)
+
+ if "text_config" not in kwargs:
+ raise ValueError("`text_config` can not be `None`.")
+
+ if "vision_config" not in kwargs:
+ raise ValueError("`vision_config` can not be `None`.")
+
+ text_config = kwargs.pop("text_config")
+ vision_config = kwargs.pop("vision_config")
+
+ text_model_type = text_config.pop("model_type")
+ vision_model_type = vision_config.pop("model_type")
+
+ from transformers import AutoConfig
+
+ self.text_config = AutoConfig.for_model(text_model_type, **text_config)
+
+ if vision_model_type == "clip":
+ self.vision_config = AutoConfig.for_model(vision_model_type, **vision_config).vision_config
+ elif vision_model_type == "clip_vision_model":
+ from transformers import CLIPVisionConfig
+
+ self.vision_config = CLIPVisionConfig(**vision_config)
+ else:
+ self.vision_config = AutoConfig.for_model(vision_model_type, **vision_config)
+
+ self.projection_dim = projection_dim
+ self.initializer_factor = 1.0
+
+ @classmethod
+ def from_text_vision_configs(cls, text_config: PretrainedConfig, vision_config: PretrainedConfig, **kwargs):
+ r"""
+ Instantiate a :class:`HybridCLIPConfig` (or a derived class) from text model configuration and
+ vision model configuration.
+
+ Returns:
+ :class:`HybridCLIPConfig`: An instance of a configuration object
+ """
+
+ return cls(text_config=text_config.to_dict(), vision_config=vision_config.to_dict(), **kwargs)
+
+ def to_dict(self):
+ """
+ Serializes this instance to a Python dictionary. Override the default
+ :meth:`~transformers.PretrainedConfig.to_dict`.
+
+ Returns:
+ :obj:`Dict[str, any]`: Dictionary of all the attributes that make up this configuration instance,
+ """
+ output = copy.deepcopy(self.__dict__)
+ output["text_config"] = self.text_config.to_dict()
+ output["vision_config"] = self.vision_config.to_dict()
+ output["model_type"] = self.__class__.model_type
+ return output
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/hybrid_clip/modeling_hybrid_clip.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/hybrid_clip/modeling_hybrid_clip.py
new file mode 100644
index 0000000000000000000000000000000000000000..08cb3bd0b3412e535a825b0e6f7a4d09362ff90a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/hybrid_clip/modeling_hybrid_clip.py
@@ -0,0 +1,420 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from typing import Optional, Tuple
+
+import flax.linen as nn
+import jax
+import jax.numpy as jnp
+from configuration_hybrid_clip import HybridCLIPConfig
+from flax.core.frozen_dict import FrozenDict
+
+from transformers import FLAX_MODEL_MAPPING, FlaxCLIPVisionModel
+from transformers.modeling_flax_utils import FlaxPreTrainedModel
+from transformers.models.clip.modeling_flax_clip import FlaxCLIPOutput
+from transformers.utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class FlaxHybridCLIPModule(nn.Module):
+ config: HybridCLIPConfig
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ text_config = self.config.text_config
+ vision_config = self.config.vision_config
+
+ self.projection_dim = self.config.projection_dim
+ self.text_embed_dim = text_config.hidden_size
+ self.vision_embed_dim = vision_config.hidden_size
+
+ text_module = FLAX_MODEL_MAPPING[self.config.text_config.__class__].module_class
+ vision_module = FLAX_MODEL_MAPPING.get(self.config.vision_config.__class__, FlaxCLIPVisionModel).module_class
+
+ self.text_model = text_module(text_config, dtype=self.dtype)
+ self.vision_model = vision_module(vision_config, dtype=self.dtype)
+
+ self.visual_projection = nn.Dense(
+ self.projection_dim,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(0.02),
+ use_bias=False,
+ )
+ self.text_projection = nn.Dense(
+ self.projection_dim,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(0.02),
+ use_bias=False,
+ )
+ self.logit_scale = self.param("logit_scale", jax.nn.initializers.ones, [])
+
+ def __call__(
+ self,
+ input_ids=None,
+ pixel_values=None,
+ attention_mask=None,
+ position_ids=None,
+ token_type_ids=None,
+ deterministic: bool = True,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ ):
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ vision_outputs = self.vision_model(
+ pixel_values=pixel_values,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ text_outputs = self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ image_embeds = vision_outputs[1]
+ image_embeds = self.visual_projection(image_embeds)
+
+ text_embeds = text_outputs[1]
+ text_embeds = self.text_projection(text_embeds)
+
+ # normalized features
+ image_embeds = image_embeds / jnp.linalg.norm(image_embeds, axis=-1, keepdims=True)
+ text_embeds = text_embeds / jnp.linalg.norm(text_embeds, axis=-1, keepdims=True)
+
+ # cosine similarity as logits
+ logit_scale = jnp.exp(self.logit_scale)
+ logits_per_text = jnp.matmul(text_embeds, image_embeds.T) * logit_scale
+ logits_per_image = logits_per_text.T
+
+ if not return_dict:
+ return (logits_per_image, logits_per_text, text_embeds, image_embeds, text_outputs, vision_outputs)
+
+ return FlaxCLIPOutput(
+ logits_per_image=logits_per_image,
+ logits_per_text=logits_per_text,
+ text_embeds=text_embeds,
+ image_embeds=image_embeds,
+ text_model_output=text_outputs,
+ vision_model_output=vision_outputs,
+ )
+
+
+class FlaxHybridCLIP(FlaxPreTrainedModel):
+ config_class = HybridCLIPConfig
+ module_class = FlaxHybridCLIPModule
+
+ def __init__(
+ self,
+ config: HybridCLIPConfig,
+ input_shape: Optional[Tuple] = None,
+ seed: int = 0,
+ dtype: jnp.dtype = jnp.float32,
+ **kwargs,
+ ):
+ if input_shape is None:
+ input_shape = ((1, 1), (1, config.vision_config.image_size, config.vision_config.image_size, 3))
+
+ module = self.module_class(config=config, dtype=dtype, **kwargs)
+ super().__init__(config, module, input_shape=input_shape, seed=seed, dtype=dtype)
+
+ def init_weights(self, rng: jax.random.PRNGKey, input_shape: Tuple, params: FrozenDict = None) -> FrozenDict:
+ # init input tensor
+ input_ids = jnp.zeros(input_shape[0], dtype="i4")
+ position_ids = jnp.broadcast_to(jnp.arange(jnp.atleast_2d(input_ids).shape[-1]), input_shape[0])
+ token_type_ids = jnp.ones_like(input_ids)
+ attention_mask = jnp.ones_like(input_ids)
+
+ pixel_values = jax.random.normal(rng, input_shape[1])
+
+ params_rng, dropout_rng = jax.random.split(rng)
+ rngs = {"params": params_rng, "dropout": dropout_rng}
+
+ return self.module.init(rngs, input_ids, pixel_values, attention_mask, position_ids, token_type_ids)["params"]
+
+ def __call__(
+ self,
+ input_ids,
+ pixel_values,
+ attention_mask=None,
+ position_ids=None,
+ token_type_ids=None,
+ params: dict = None,
+ dropout_rng: jax.random.PRNGKey = None,
+ train: bool = False,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ):
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ if position_ids is None:
+ position_ids = jnp.broadcast_to(jnp.arange(jnp.atleast_2d(input_ids).shape[-1]), input_ids.shape)
+
+ if token_type_ids is None:
+ token_type_ids = jnp.zeros_like(input_ids)
+
+ if attention_mask is None:
+ attention_mask = jnp.ones_like(input_ids)
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ return self.module.apply(
+ {"params": params or self.params},
+ jnp.array(input_ids, dtype="i4"),
+ jnp.array(pixel_values, dtype=jnp.float32),
+ jnp.array(attention_mask, dtype="i4"),
+ jnp.array(position_ids, dtype="i4"),
+ jnp.array(token_type_ids, dtype="i4"),
+ not train,
+ output_attentions,
+ output_hidden_states,
+ return_dict,
+ rngs=rngs,
+ )
+
+ def get_text_features(
+ self,
+ input_ids,
+ attention_mask=None,
+ position_ids=None,
+ token_type_ids=None,
+ params: dict = None,
+ dropout_rng: jax.random.PRNGKey = None,
+ train=False,
+ ):
+ r"""
+ Args:
+ input_ids (:obj:`numpy.ndarray` of shape :obj:`(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you
+ provide it.
+
+ Indices can be obtained using :class:`~transformers.PreTrainedTokenizer`. See
+ :meth:`transformers.PreTrainedTokenizer.encode` and :meth:`transformers.PreTrainedTokenizer.__call__`
+ for details.
+
+ `What are input IDs? <../glossary.html#input-ids>`__
+
+ Returns:
+ text_features (:obj:`jnp.ndarray` of shape :obj:`(batch_size, output_dim`): The text embeddings
+ obtained by applying the projection layer to the pooled output of text model.
+ """
+ if position_ids is None:
+ position_ids = jnp.broadcast_to(jnp.arange(jnp.atleast_2d(input_ids).shape[-1]), input_ids.shape)
+
+ if token_type_ids is None:
+ token_type_ids = jnp.zeros_like(input_ids)
+
+ if attention_mask is None:
+ attention_mask = jnp.ones_like(input_ids)
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ def _get_features(module, input_ids, attention_mask, position_ids, token_type_ids, deterministic):
+ text_outputs = module.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ token_type_ids=token_type_ids,
+ deterministic=deterministic,
+ )
+ pooled_output = text_outputs[1]
+ text_features = module.text_projection(pooled_output)
+ return text_features
+
+ return self.module.apply(
+ {"params": params or self.params},
+ jnp.array(input_ids, dtype="i4"),
+ jnp.array(attention_mask, dtype="i4"),
+ jnp.array(position_ids, dtype="i4"),
+ jnp.array(token_type_ids, dtype="i4"),
+ not train,
+ method=_get_features,
+ rngs=rngs,
+ )
+
+ def get_image_features(
+ self, pixel_values, params: dict = None, dropout_rng: jax.random.PRNGKey = None, train=False
+ ):
+ r"""
+ Args:
+ pixel_values (:obj:`numpy.ndarray` of shape :obj:`(batch_size, num_channels, height, width)`):
+ Pixel values. Padding will be ignored by default should you provide it. Pixel values can be obtained
+ using :class:`~transformers.ImageFeatureExtractionMixin`. See
+ :meth:`transformers.ImageFeatureExtractionMixin.__call__` for details.
+
+ Returns:
+ image_features (:obj:`jnp.ndarray` of shape :obj:`(batch_size, output_dim`): The image embeddings
+ obtained by applying the projection layer to the pooled output of vision model.
+ """
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ def _get_features(module, pixel_values, deterministic):
+ vision_outputs = module.vision_model(pixel_values=pixel_values, deterministic=deterministic)
+ pooled_output = vision_outputs[1] # pooled_output
+ image_features = module.visual_projection(pooled_output)
+ return image_features
+
+ return self.module.apply(
+ {"params": params or self.params},
+ jnp.array(pixel_values, dtype=jnp.float32),
+ not train,
+ method=_get_features,
+ rngs=rngs,
+ )
+
+ @classmethod
+ def from_text_vision_pretrained(
+ cls,
+ text_model_name_or_path: str = None,
+ vision_model_name_or_path: str = None,
+ *model_args,
+ **kwargs,
+ ) -> FlaxPreTrainedModel:
+ """
+ Params:
+ text_model_name_or_path (:obj: `str`, `optional`):
+ Information necessary to initiate the text model. Can be either:
+
+ - A string, the `model id` of a pretrained model hosted inside a model repo on huggingface.co.
+ - A path to a `directory` containing model weights saved using
+ :func:`~transformers.FlaxPreTrainedModel.save_pretrained`, e.g., ``./my_model_directory/``.
+ - A path or url to a `PyTorch checkpoint folder` (e.g, ``./pt_model``). In
+ this case, ``from_pt`` should be set to :obj:`True` and a configuration object should be provided
+ as ``config`` argument. This loading path is slower than converting the PyTorch checkpoint in
+ a Flax model using the provided conversion scripts and loading the Flax model afterwards.
+
+ vision_model_name_or_path (:obj: `str`, `optional`, defaults to `None`):
+ Information necessary to initiate the vision model. Can be either:
+
+ - A string, the `model id` of a pretrained model hosted inside a model repo on huggingface.co.
+ - A path to a `directory` containing model weights saved using
+ :func:`~transformers.FlaxPreTrainedModel.save_pretrained`, e.g., ``./my_model_directory/``.
+ - A path or url to a `PyTorch checkpoint folder` (e.g, ``./pt_model``). In
+ this case, ``from_pt`` should be set to :obj:`True` and a configuration object should be provided
+ as ``config`` argument. This loading path is slower than converting the PyTorch checkpoint in
+ a Flax model using the provided conversion scripts and loading the Flax model afterwards.
+
+ model_args (remaining positional arguments, `optional`):
+ All remaning positional arguments will be passed to the underlying model's ``__init__`` method.
+
+ kwargs (remaining dictionary of keyword arguments, `optional`):
+ Can be used to update the configuration object (after it being loaded) and initiate the model (e.g.,
+ :obj:`output_attentions=True`).
+
+ - To update the text configuration, use the prefix `text_` for each configuration parameter.
+ - To update the vision configuration, use the prefix `vision_` for each configuration parameter.
+ - To update the parent model configuration, do not use a prefix for each configuration parameter.
+
+ Behaves differently depending on whether a :obj:`config` is provided or automatically loaded.
+
+ Example::
+
+ >>> from transformers import FlaxHybridCLIP
+ >>> # initialize a model from pretrained BERT and CLIP models. Note that the projection layers will be randomly initialized.
+ >>> # If using CLIP's vision model the vision projection layer will be initialized using pre-trained weights
+ >>> model = FlaxHybridCLIP.from_text_vision_pretrained('google-bert/bert-base-uncased', 'openai/clip-vit-base-patch32')
+ >>> # saving model after fine-tuning
+ >>> model.save_pretrained("./bert-clip")
+ >>> # load fine-tuned model
+ >>> model = FlaxHybridCLIP.from_pretrained("./bert-clip")
+ """
+
+ kwargs_text = {
+ argument[len("text_") :]: value for argument, value in kwargs.items() if argument.startswith("text_")
+ }
+
+ kwargs_vision = {
+ argument[len("vision_") :]: value for argument, value in kwargs.items() if argument.startswith("vision_")
+ }
+
+ # remove text, vision kwargs from kwargs
+ for key in kwargs_text.keys():
+ del kwargs["text_" + key]
+ for key in kwargs_vision.keys():
+ del kwargs["vision_" + key]
+
+ # Load and initialize the text and vision model
+ text_model = kwargs_text.pop("model", None)
+ if text_model is None:
+ assert (
+ text_model_name_or_path is not None
+ ), "If `model` is not defined as an argument, a `text_model_name_or_path` has to be defined"
+ from transformers import FlaxAutoModel
+
+ if "config" not in kwargs_text:
+ from transformers import AutoConfig
+
+ text_config = AutoConfig.from_pretrained(text_model_name_or_path)
+ kwargs_text["config"] = text_config
+
+ text_model = FlaxAutoModel.from_pretrained(text_model_name_or_path, *model_args, **kwargs_text)
+
+ vision_model = kwargs_vision.pop("model", None)
+ if vision_model is None:
+ assert (
+ vision_model_name_or_path is not None
+ ), "If `model` is not defined as an argument, a `vision_model_name_or_path` has to be defined"
+ from transformers import FlaxAutoModel
+
+ if "config" not in kwargs_vision:
+ from transformers import AutoConfig
+
+ vision_config = AutoConfig.from_pretrained(vision_model_name_or_path)
+ kwargs_vision["config"] = vision_config
+
+ vision_model = FlaxAutoModel.from_pretrained(vision_model_name_or_path, *model_args, **kwargs_vision)
+
+ # instantiate config with corresponding kwargs
+ dtype = kwargs.pop("dtype", jnp.float32)
+ config = HybridCLIPConfig.from_text_vision_configs(text_model.config, vision_model.config, **kwargs)
+
+ # init model
+ model = cls(config, *model_args, dtype=dtype, **kwargs)
+
+ if vision_config.model_type == "clip":
+ model.params["vision_model"]["vision_model"] = vision_model.params["vision_model"]
+ model.params["visual_projection"]["kernel"] = vision_model.params["visual_projection"]["kernel"]
+ else:
+ model.params["vision_model"] = vision_model.params
+
+ model.params["text_model"] = text_model.params
+
+ return model
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/hybrid_clip/requirements.txt b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/hybrid_clip/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..7b465dde645e6d9baaee1e750a28b45e03cc50d2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/hybrid_clip/requirements.txt
@@ -0,0 +1,8 @@
+jax>=0.2.8
+jaxlib>=0.1.59
+flax>=0.3.5
+optax>=0.0.8
+-f https://download.pytorch.org/whl/torch_stable.html
+torch==2.2.0
+-f https://download.pytorch.org/whl/torch_stable.html
+torchvision==0.10.0+cpu
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/hybrid_clip/run_hybrid_clip.py b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/hybrid_clip/run_hybrid_clip.py
new file mode 100644
index 0000000000000000000000000000000000000000..2020f0a35c40a4a40dc366ca1b89d2dfecd1b254
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/hybrid_clip/run_hybrid_clip.py
@@ -0,0 +1,576 @@
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2021 The HuggingFace Team All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Training a CLIP like dual encoder models using text and vision encoders in the library.
+
+The script can be used to train CLIP like models for languages other than english by using
+a text encoder pre-trained in the desired language. Currently this script support the following vision
+and text models:
+Vision models: ViT(https://huggingface.co/models?filter=vit), CLIP (https://huggingface.co/models?filter=clip)
+Text models: BERT, ROBERTa (https://huggingface.co/models?filter=fill-mask)
+"""
+
+import json
+import logging
+import os
+import sys
+import time
+from dataclasses import dataclass, field
+from pathlib import Path
+from typing import Callable, Optional
+
+import jax
+import jax.numpy as jnp
+import optax
+import torch
+from flax import jax_utils
+from flax.jax_utils import unreplicate
+from flax.training import train_state
+from flax.training.common_utils import get_metrics, shard, shard_prng_key
+from modeling_hybrid_clip import FlaxHybridCLIP
+from torchvision.datasets import VisionDataset
+from torchvision.io import ImageReadMode, read_image
+from torchvision.transforms import CenterCrop, ConvertImageDtype, Normalize, Resize
+from torchvision.transforms.functional import InterpolationMode
+from tqdm import tqdm
+
+import transformers
+from transformers import AutoTokenizer, HfArgumentParser, TrainingArguments, is_tensorboard_available, set_seed
+
+
+logger = logging.getLogger(__name__)
+
+# Cache the result
+has_tensorboard = is_tensorboard_available()
+if has_tensorboard:
+ try:
+ from flax.metrics.tensorboard import SummaryWriter
+ except ImportError as ie:
+ has_tensorboard = False
+ print(f"Unable to display metrics through TensorBoard because some package are not installed: {ie}")
+
+else:
+ print(
+ "Unable to display metrics through TensorBoard because the package is not installed: "
+ "Please run pip install tensorboard to enable."
+ )
+
+
+@dataclass
+class ModelArguments:
+ """
+ Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
+ """
+
+ text_model_name_or_path: str = field(
+ metadata={
+ "help": (
+ "The text model checkpoint for weights initialization. "
+ "Don't set if you want to train a model from scratch."
+ )
+ },
+ )
+ vision_model_name_or_path: str = field(
+ metadata={
+ "help": (
+ "The vision model checkpoint for weights initialization. "
+ "Don't set if you want to train a model from scratch."
+ )
+ },
+ )
+ from_pt: bool = field(
+ default=True,
+ metadata={"help": "whether to load the text and vision model using PyTorch checkpoints."},
+ )
+ config_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
+ )
+ tokenizer_name: Optional[str] = field(
+ default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
+ )
+ cache_dir: Optional[str] = field(
+ default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
+ )
+ use_fast_tokenizer: bool = field(
+ default=True,
+ metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
+ )
+ dtype: Optional[str] = field(
+ default="float32",
+ metadata={
+ "help": (
+ "Floating-point format in which the model weights should be initialized and trained. Choose one of"
+ " `[float32, float16, bfloat16]`."
+ )
+ },
+ )
+
+
+@dataclass
+class DataTrainingArguments:
+ """
+ Arguments pertaining to what data we are going to input our model for training and eval.
+ """
+
+ data_dir: Optional[str] = field(default=None, metadata={"help": "The data directory containing input files."})
+ train_file: Optional[str] = field(
+ default=None, metadata={"help": "The input training data file (a jsonlines file)."}
+ )
+ validation_file: Optional[str] = field(
+ default=None,
+ metadata={"help": "An optional input evaluation data file (a jsonlines file)."},
+ )
+ max_seq_length: Optional[int] = field(
+ default=72,
+ metadata={
+ "help": (
+ "The maximum total input sequence length after tokenization. Sequences longer "
+ "than this will be truncated, sequences shorter will be padded."
+ )
+ },
+ )
+ max_train_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ )
+ },
+ )
+ max_eval_samples: Optional[int] = field(
+ default=None,
+ metadata={
+ "help": (
+ "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
+ "value if set."
+ )
+ },
+ )
+ overwrite_cache: bool = field(
+ default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
+ )
+ preprocessing_num_workers: Optional[int] = field(
+ default=None,
+ metadata={"help": "The number of processes to use for the preprocessing."},
+ )
+
+ def __post_init__(self):
+ if self.train_file is None and self.validation_file is None:
+ raise ValueError("Need either a dataset name or a training/validation file.")
+ else:
+ if self.train_file is not None:
+ extension = self.train_file.split(".")[-1]
+ assert extension == "json", "`train_file` should be a json file."
+ if self.validation_file is not None:
+ extension = self.validation_file.split(".")[-1]
+ assert extension == "json", "`validation_file` should be a json file."
+
+
+# We use torchvision for faster image pre-processing.
+# We need to ensure faster processing speed as it can become a bottleneck on TPU
+class Transform(torch.nn.Module):
+ def __init__(self, image_size):
+ super().__init__()
+ self.transforms = torch.nn.Sequential(
+ Resize([image_size], interpolation=InterpolationMode.BICUBIC),
+ CenterCrop(image_size),
+ ConvertImageDtype(torch.float),
+ Normalize((0.48145466, 0.4578275, 0.40821073), (0.26862954, 0.26130258, 0.27577711)),
+ )
+
+ def forward(self, x: torch.Tensor) -> torch.Tensor:
+ with torch.no_grad():
+ x = self.transforms(x)
+ return x
+
+
+class ImageTextDataset(VisionDataset):
+ """
+ Dtaset for loading image-text data for tasks like CLIP training, Image Captioning.
+
+ Args:
+ root: (string): The root path where the dataset is stored
+ file_path: (string): Path to the file containing the image_paths and associated captions.
+ The expected format is jsonlines where each line is a json object containing to keys.
+ `image_path`: The path to the image.
+ `captions`: An `array` of captions.
+ transform (callable, optional): A function/transform that takes in an PIL image
+ and returns a transformed version. E.g, ``transforms.ToTensor``
+ target_transform (callable, optional): A function/transform that takes in the
+ target and transforms it.
+ transforms (callable, optional): A function/transform that takes input sample and its target as entry
+ and returns a transformed version.
+ """
+
+ def __init__(
+ self,
+ root: str,
+ file_path: str,
+ captions_per_image=2,
+ transform: Optional[Callable] = None,
+ target_transform: Optional[Callable] = None,
+ transforms: Optional[Callable] = None,
+ ):
+ super().__init__(root, transforms, transform, target_transform)
+
+ with open(file_path, "r") as f:
+ examples = [json.loads(line) for line in f.readlines()]
+
+ self.captions = []
+ self.image_paths = []
+
+ for example in examples:
+ captions_subset = example["captions"][:captions_per_image]
+ self.captions.extend(captions_subset)
+ self.image_paths.extend([example["image_path"]] * len(captions_subset))
+
+ def _load_image(self, idx: int):
+ path = self.image_paths[idx]
+ return read_image(path, mode=ImageReadMode.RGB)
+
+ def _load_target(self, idx):
+ return self.captions[idx]
+
+ def __getitem__(self, index: int):
+ image = self._load_image(index)
+ target = self._load_target(index)
+
+ if self.transforms is not None:
+ image, target = self.transforms(image, target)
+
+ return image, target
+
+ def __len__(self) -> int:
+ return len(self.captions)
+
+
+class TrainState(train_state.TrainState):
+ dropout_rng: jnp.ndarray
+
+ def replicate(self):
+ return jax_utils.replicate(self).replace(dropout_rng=shard_prng_key(self.dropout_rng))
+
+
+def write_metric(summary_writer, train_metrics, eval_metrics, train_time, step):
+ summary_writer.scalar("train_time", train_time, step)
+
+ train_metrics = get_metrics(train_metrics)
+ for key, vals in train_metrics.items():
+ tag = f"train_{key}"
+ for i, val in enumerate(vals):
+ summary_writer.scalar(tag, val, step - len(vals) + i + 1)
+
+ for metric_name, value in eval_metrics.items():
+ summary_writer.scalar(f"eval_{metric_name}", value, step)
+
+
+def create_learning_rate_fn(
+ train_ds_size: int, train_batch_size: int, num_train_epochs: int, num_warmup_steps: int, learning_rate: float
+) -> Callable[[int], jnp.ndarray]:
+ """Returns a linear warmup, linear_decay learning rate function."""
+ steps_per_epoch = train_ds_size // train_batch_size
+ num_train_steps = steps_per_epoch * num_train_epochs
+ warmup_fn = optax.linear_schedule(init_value=0.0, end_value=learning_rate, transition_steps=num_warmup_steps)
+ decay_fn = optax.linear_schedule(
+ init_value=learning_rate, end_value=0, transition_steps=num_train_steps - num_warmup_steps
+ )
+ schedule_fn = optax.join_schedules(schedules=[warmup_fn, decay_fn], boundaries=[num_warmup_steps])
+ return schedule_fn
+
+
+def main():
+ parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
+ if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
+ # If we pass only one argument to the script and it's the path to a json file,
+ # let's parse it to get our arguments.
+ model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
+ else:
+ model_args, data_args, training_args = parser.parse_args_into_dataclasses()
+
+ if (
+ os.path.exists(training_args.output_dir)
+ and os.listdir(training_args.output_dir)
+ and training_args.do_train
+ and not training_args.overwrite_output_dir
+ ):
+ raise ValueError(
+ f"Output directory ({training_args.output_dir}) already exists and is not empty. "
+ "Use --overwrite_output_dir to overcome."
+ )
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ # Setup logging, we only want one process per machine to log things on the screen.
+ logger.setLevel(logging.INFO if jax.process_index() == 0 else logging.ERROR)
+ if jax.process_index() == 0:
+ transformers.utils.logging.set_verbosity_info()
+ else:
+ transformers.utils.logging.set_verbosity_error()
+
+ # Set the verbosity to info of the Transformers logger (on main process only):
+ logger.info(f"Training/evaluation parameters {training_args}")
+
+ if model_args.tokenizer_name:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.tokenizer_name, cache_dir=model_args.cache_dir, use_fast=model_args.use_fast_tokenizer
+ )
+ elif model_args.text_model_name_or_path:
+ tokenizer = AutoTokenizer.from_pretrained(
+ model_args.text_model_name_or_path, cache_dir=model_args.cache_dir, use_fast=model_args.use_fast_tokenizer
+ )
+ else:
+ raise ValueError(
+ "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
+ "You can do it from another script, save it, and load it from here, using --tokenizer_name."
+ )
+
+ model = FlaxHybridCLIP.from_text_vision_pretrained(
+ model_args.text_model_name_or_path,
+ model_args.vision_model_name_or_path,
+ seed=training_args.seed,
+ dtype=getattr(jnp, model_args.dtype),
+ text_from_pt=model_args.from_pt,
+ vision_from_pt=model_args.from_pt,
+ )
+ config = model.config
+ # set seed for torch dataloaders
+ set_seed(training_args.seed)
+
+ # Initialize torchvision transforms and jit them for faster processing
+ preprocess = Transform(config.vision_config.image_size)
+ preprocess = torch.jit.script(preprocess)
+
+ # Initialize the image-text dataset
+ train_dataset = ImageTextDataset(
+ data_args.data_dir,
+ data_args.train_file,
+ captions_per_image=2,
+ transform=preprocess,
+ )
+
+ eval_dataset = ImageTextDataset(
+ data_args.data_dir,
+ data_args.validation_file,
+ captions_per_image=1,
+ transform=preprocess,
+ )
+
+ # Store some constant
+ num_epochs = int(training_args.num_train_epochs)
+ train_batch_size = int(training_args.per_device_train_batch_size) * jax.device_count()
+ eval_batch_size = int(training_args.per_device_eval_batch_size) * jax.device_count()
+ steps_per_epoch = len(train_dataset) // train_batch_size
+ total_train_steps = steps_per_epoch * num_epochs
+
+ # Use collate function to tokenizer the text and convert the processed images to numpy
+ def collate_fn(examples):
+ pixel_values = torch.stack([example[0] for example in examples]).permute(0, 2, 3, 1).numpy()
+ captions = [example[1] for example in examples]
+ inputs = tokenizer(
+ captions, max_length=data_args.max_seq_length, padding="max_length", truncation=True, return_tensors="np"
+ )
+
+ batch = {
+ "pixel_values": pixel_values,
+ "input_ids": inputs["input_ids"],
+ "attention_mask": inputs["attention_mask"],
+ }
+
+ return batch
+
+ # Create data loaders
+ train_loader = torch.utils.data.DataLoader(
+ train_dataset,
+ batch_size=train_batch_size,
+ shuffle=True,
+ num_workers=data_args.preprocessing_num_workers,
+ persistent_workers=True,
+ drop_last=True,
+ collate_fn=collate_fn,
+ )
+
+ eval_loader = torch.utils.data.DataLoader(
+ eval_dataset,
+ batch_size=eval_batch_size,
+ shuffle=False,
+ num_workers=data_args.preprocessing_num_workers,
+ persistent_workers=True,
+ drop_last=True,
+ collate_fn=collate_fn,
+ )
+
+ # Enable tensorboard only on the master node
+ if has_tensorboard and jax.process_index() == 0:
+ summary_writer = SummaryWriter(log_dir=Path(training_args.output_dir).joinpath("logs").as_posix())
+
+ # Initialize our training
+ rng = jax.random.PRNGKey(training_args.seed)
+ rng, dropout_rng = jax.random.split(rng)
+
+ # Create learning rate schedule
+ linear_decay_lr_schedule_fn = create_learning_rate_fn(
+ len(train_dataset),
+ train_batch_size,
+ training_args.num_train_epochs,
+ training_args.warmup_steps,
+ training_args.learning_rate,
+ )
+
+ # create adam optimizer
+ adamw = optax.adamw(
+ learning_rate=linear_decay_lr_schedule_fn,
+ b1=training_args.adam_beta1,
+ b2=training_args.adam_beta2,
+ eps=training_args.adam_epsilon,
+ weight_decay=training_args.weight_decay,
+ )
+
+ # Setup train state
+ state = TrainState.create(apply_fn=model.__call__, params=model.params, tx=adamw, dropout_rng=dropout_rng)
+
+ def cross_entropy(logits, axis):
+ logprobs = jax.nn.log_softmax(logits, axis=axis)
+ nll = jnp.diag(logprobs)
+ ce = -jnp.mean(nll)
+ return ce
+
+ def clip_loss(similarity):
+ loss = (cross_entropy(similarity, axis=0) + cross_entropy(similarity, axis=1)) / 2
+ return loss
+
+ # Define gradient update step fn
+ def train_step(state, batch):
+ dropout_rng, new_dropout_rng = jax.random.split(state.dropout_rng)
+
+ def compute_loss(params):
+ logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
+ loss = clip_loss(logits)
+ return loss
+
+ grad_fn = jax.value_and_grad(compute_loss)
+ loss, grad = grad_fn(state.params)
+ grad = jax.lax.pmean(grad, "batch")
+
+ new_state = state.apply_gradients(grads=grad, dropout_rng=new_dropout_rng)
+
+ metrics = {"loss": loss, "learning_rate": linear_decay_lr_schedule_fn(state.step)}
+ metrics = jax.lax.pmean(metrics, axis_name="batch")
+
+ return new_state, metrics
+
+ # Define eval fn
+ def eval_step(params, batch):
+ logits = model(**batch, params=params, train=False)[0]
+ loss = clip_loss(logits)
+
+ # summarize metrics
+ metrics = {"loss": loss}
+ metrics = jax.lax.pmean(metrics, axis_name="batch")
+ return metrics
+
+ # Create parallel version of the train and eval step
+ p_train_step = jax.pmap(train_step, "batch", donate_argnums=(0,))
+ p_eval_step = jax.pmap(eval_step, "batch")
+
+ # Replicate the train state on each device
+ state = state.replicate()
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {num_epochs}")
+ logger.info(f" Instantaneous batch size per device = {training_args.per_device_train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel & distributed) = {train_batch_size}")
+ logger.info(f" Total optimization steps = {total_train_steps}")
+
+ train_time = 0
+ # Create sampling rng
+ rng, input_rng = jax.random.split(rng)
+
+ epochs = tqdm(range(num_epochs), desc=f"Epoch ... (1/{num_epochs})", position=0)
+ for epoch in epochs:
+ # ======================== Training ================================
+ train_start = time.time()
+
+ # Create sampling rng
+ rng, input_rng = jax.random.split(rng)
+ train_metrics = []
+
+ steps_per_epoch = len(train_dataset) // train_batch_size
+ train_step_progress_bar = tqdm(total=steps_per_epoch, desc="Training...", position=1, leave=False)
+ # train
+ for batch in train_loader:
+ batch = shard(batch)
+ state, train_metric = p_train_step(state, batch)
+ train_metrics.append(train_metric)
+
+ train_step_progress_bar.update(1)
+
+ train_time += time.time() - train_start
+
+ train_metric = unreplicate(train_metric)
+
+ train_step_progress_bar.close()
+ epochs.write(
+ f"Epoch... ({epoch + 1}/{num_epochs} | Loss: {train_metric['loss']}, Learning Rate:"
+ f" {train_metric['learning_rate']})"
+ )
+
+ # ======================== Evaluating ==============================
+ eval_metrics = []
+ eval_steps = len(eval_dataset) // eval_batch_size
+ eval_step_progress_bar = tqdm(total=eval_steps, desc="Evaluating...", position=2, leave=False)
+ for batch in eval_loader:
+ # Model forward
+ batch = shard(batch)
+ metrics = p_eval_step(state.params, batch)
+ eval_metrics.append(metrics)
+
+ eval_step_progress_bar.update(1)
+
+ # normalize eval metrics
+ eval_metrics = get_metrics(eval_metrics)
+
+ eval_metrics = jax.tree_util.tree_map(jnp.mean, eval_metrics)
+
+ # Print metrics and update progress bar
+ eval_step_progress_bar.close()
+ desc = f"Epoch... ({epoch + 1}/{num_epochs} | Eval Loss: {eval_metrics['loss']})"
+ epochs.write(desc)
+ epochs.desc = desc
+
+ # Save metrics
+ if has_tensorboard and jax.process_index() == 0:
+ cur_step = epoch * (len(train_dataset) // train_batch_size)
+ write_metric(summary_writer, train_metrics, eval_metrics, train_time, cur_step)
+
+ # save checkpoint after each epoch and push checkpoint to the hub
+ if jax.process_index() == 0:
+ params = jax.device_get(unreplicate(state.params))
+ model.save_pretrained(
+ training_args.output_dir,
+ params=params,
+ push_to_hub=training_args.push_to_hub,
+ commit_message=f"Saving weights and logs of epoch {epoch+1}",
+ )
+
+
+if __name__ == "__main__":
+ main()
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/model_parallel/README.md b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/model_parallel/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..393c9e8937508562b15daeee15029c20617f72a0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/examples/research_projects/jax-projects/model_parallel/README.md
@@ -0,0 +1,67 @@
+
+
+# Model parallel language model training example
+
+The following example showcases how to train/fine-tune GPTNeo model with model parallelism using
+the JAX/Flax backend and the [`pjit`](https://jax.readthedocs.io/en/latest/jax.experimental.pjit.html) transformation.
+
+> Note: The example is experimental and might have bugs. Also currently it only supports single V3-8.
+
+The `partition.py` file defines the `PyTree` of `ParitionSpec` for the GPTNeo model which describes how the model will be sharded.
+The actual sharding is auto-matically handled by `pjit`. The weights are sharded across all local devices.
+To adapt the script for other models, we need to also change the `ParitionSpec` accordingly.
+
+TODO: Add more explantion.
+
+Before training, let's prepare our model first. To be able to shard the model, the sharded dimension needs to be a multiple of devices it'll be sharded on. But GPTNeo's vocab size is 50257, so we need to resize the embeddings accordingly.
+
+```python
+from transformers import FlaxGPTNeoForCausalLM, GPTNeoConfig
+model = FlaxGPTNeoForCausalLM.from_pretrained("EleutherAI/gpt-neo-1.3B")
+
+emb = jnp.zeros((50264, model.config.hidden_size))
+# update the first 50257 weights using pre-trained weights
+emb = emb.at[:50257, :].set(model.params["transformer"]["wte"]["embedding"])
+params = model.params
+params["transformer"]["wte"]["embedding"] = emb
+
+# initialize a random model with the right vocab_size
+config = GPTNeoConfig.from_pretrained("EleutherAI/gpt-neo-1.3B", vocab_size=50264)
+model = FlaxGPTNeoForCausalLM(config)
+
+# assign the pre-trained weights and save the model.
+model.params = params
+model.save_pretrained("gpt-neo-1.3B")
+```
+
+
+### Train Model
+
+```bash
+python run_clm_mp.py \
+ --model_name_or_path gpt-neo-1.3B \
+ --tokenizer_name openai-community/gpt2 \
+ --dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 \
+ --do_train --do_eval \
+ --block_size 1024 \
+ --num_train_epochs 5 \
+ --learning_rate 4e-6 \
+ --per_device_train_batch_size 3 --per_device_eval_batch_size 3 \
+ --overwrite_output_dir --output_dir ~/tmp/flax-clm \
+ --cache_dir ~/datasets_cache/wikitext --dtype bfloat16 \
+ --logging_steps 96 --eval_steps 96
+```
\ No newline at end of file
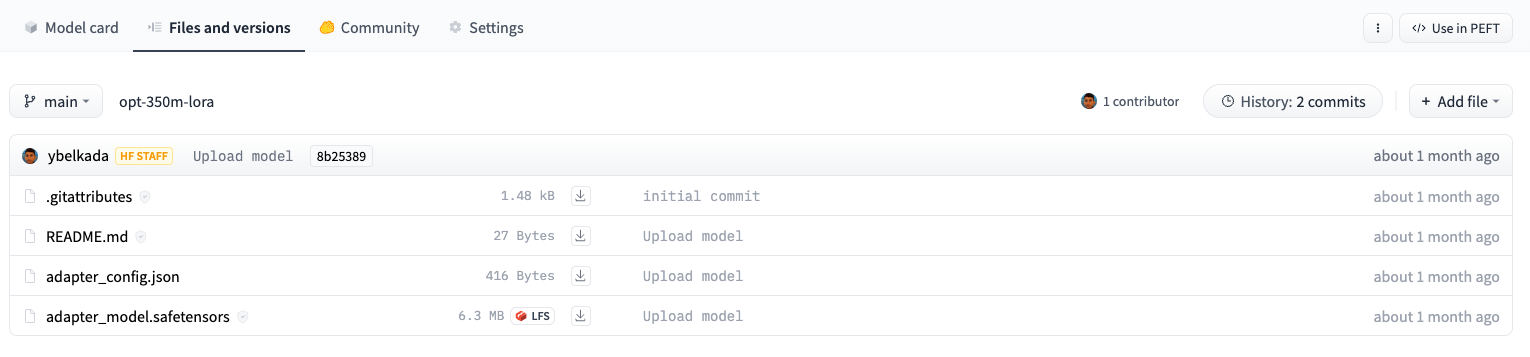 +
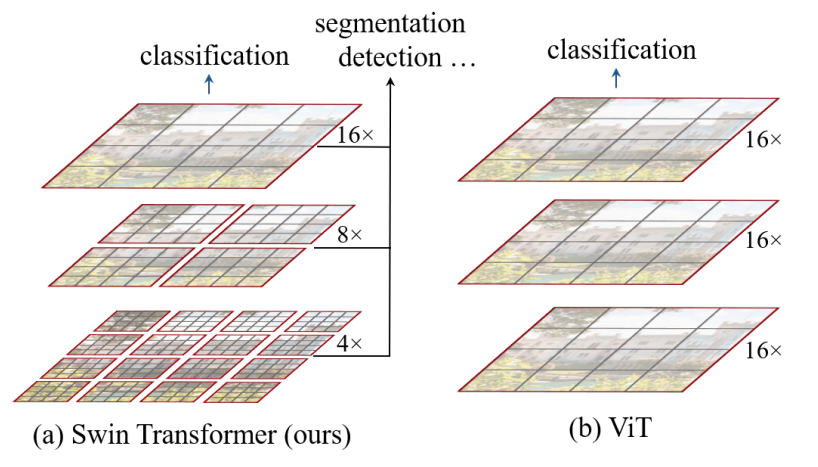 +
+ Swin Transformer 아키텍처. 원본 논문에서 발췌.
+
+이 모델은 [novice03](https://huggingface.co/novice03)이 기여하였습니다. Tensorflow 버전은 [amyeroberts](https://huggingface.co/amyeroberts)가 기여했습니다. 원본 코드는 [여기](https://github.com/microsoft/Swin-Transformer)에서 확인할 수 있습니다.
+
+## 사용 팁 [[usage-tips]]
+
+- Swin은 입력의 높이와 너비가 `32`로 나누어질 수 있으면 어떤 크기든 지원할 수 있도록 패딩을 추가합니다.
+- Swin은 *백본*으로 사용할 수 있습니다. `output_hidden_states = True`로 설정하면, `hidden_states`와 `reshaped_hidden_states`를 모두 출력합니다. `reshaped_hidden_states`는 `(batch, num_channels, height, width)` 형식을 가지며, 이는 `(batch_size, sequence_length, num_channels)` 형식과 다릅니다.
+
+## 리소스 [[resources]]
+
+Swin Transformer의 사용을 도울 수 있는 Hugging Face 및 커뮤니티(🌎로 표시)의 공식 자료 목록입니다.
+
+
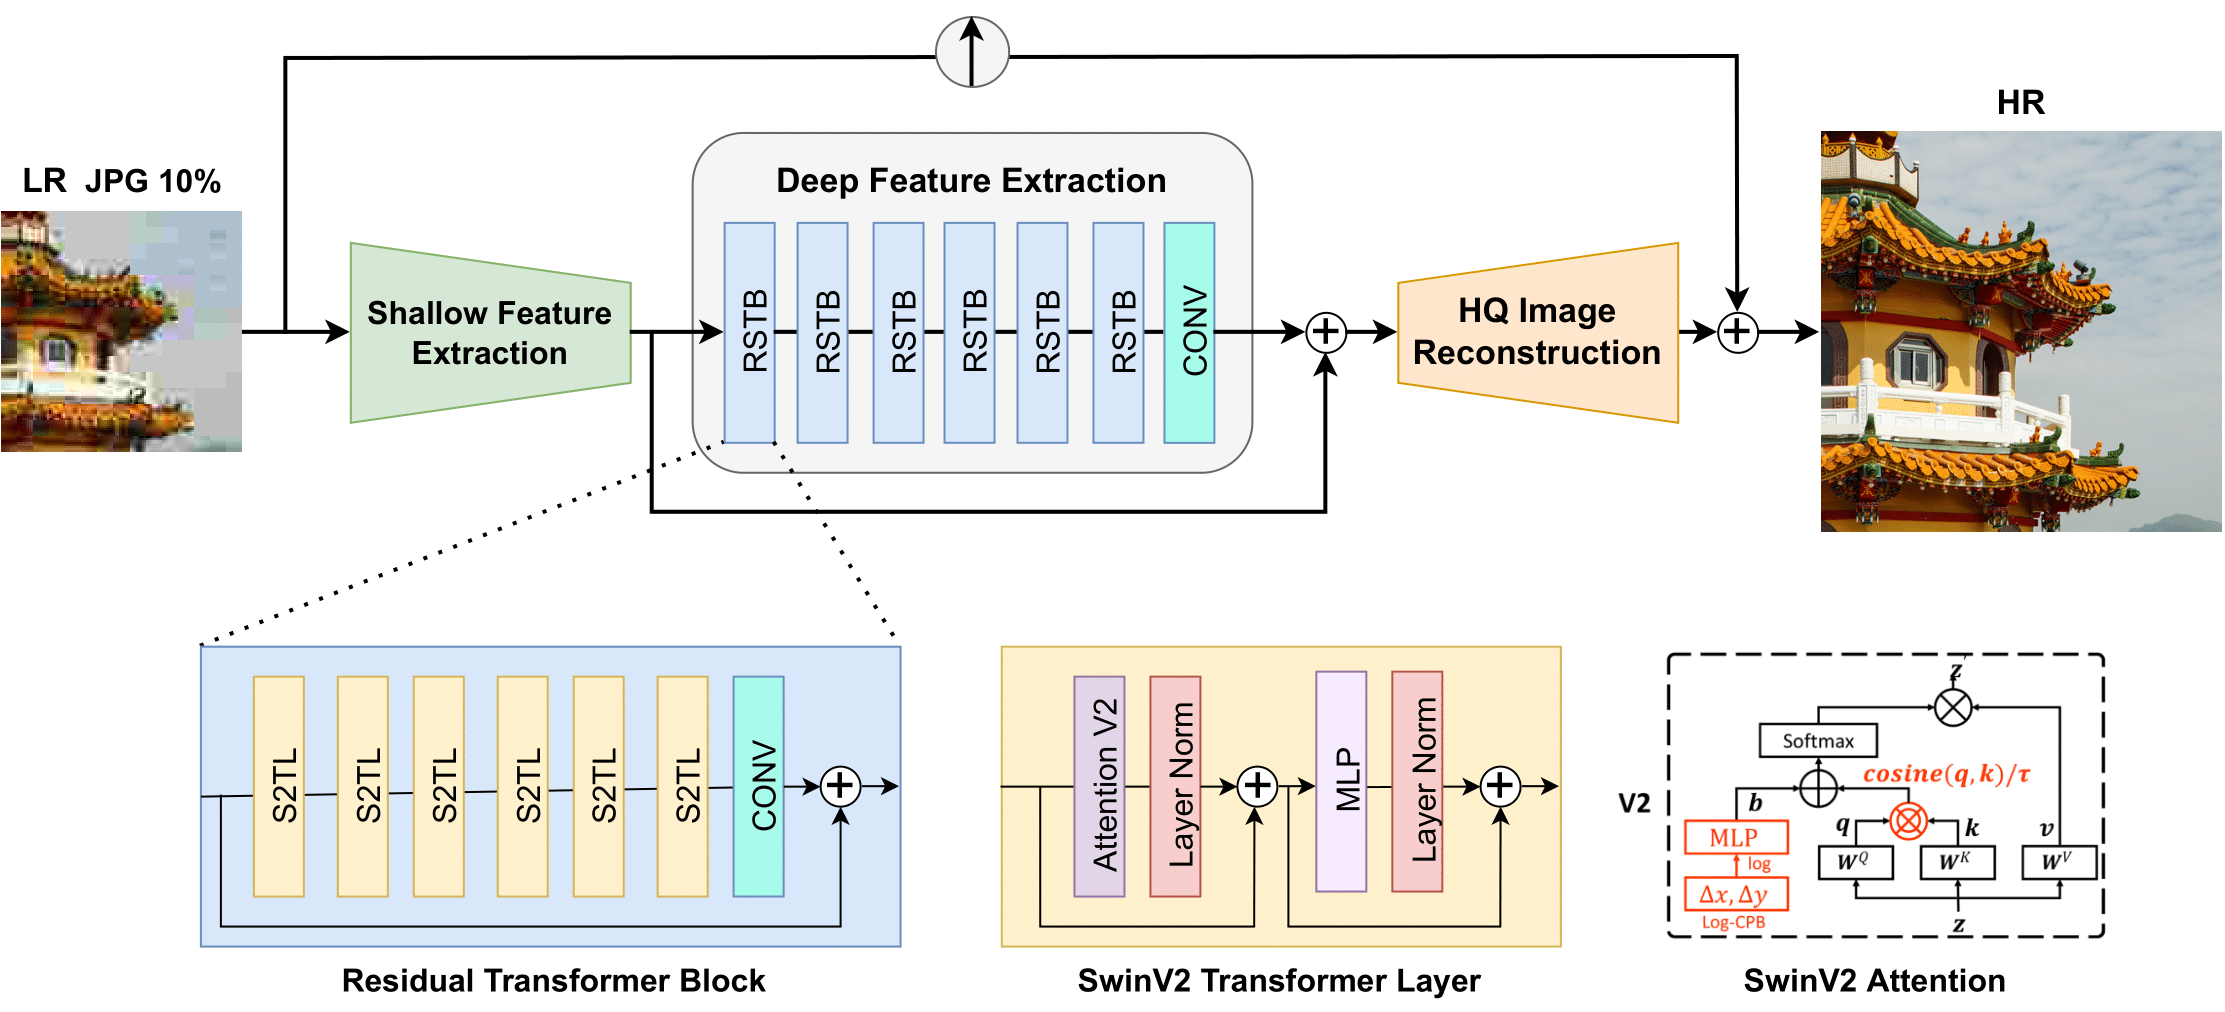 +
+ Swin2SR 아키텍처. 원본 논문에서 발췌.
+
+이 모델은 [nielsr](https://huggingface.co/nielsr)가 기여하였습니다.
+원본 코드는 [여기](https://github.com/mv-lab/swin2sr)에서 확인할 수 있습니다.
+
+## 리소스 [[resources]]
+
+Swin2SR demo notebook은 [여기](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Swin2SR)에서 확인할 수 있습니다.
+
+SwinSR을 활용한 image super-resolution demo space는 [여기](https://huggingface.co/spaces/jjourney1125/swin2sr)에서 확인할 수 있습니다.
+
+## Swin2SRImageProcessor [[transformers.Swin2SRImageProcessor]]
+
+[[autodoc]] Swin2SRImageProcessor
+ - preprocess
+
+## Swin2SRConfig [[transformers.Swin2SRConfig]]
+
+[[autodoc]] Swin2SRConfig
+
+## Swin2SRModel [[transformers.Swin2SRModel]]
+
+[[autodoc]] Swin2SRModel
+ - forward
+
+## Swin2SRForImageSuperResolution [[transformers.Swin2SRForImageSuperResolution]]
+
+[[autodoc]] Swin2SRForImageSuperResolution
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/swinv2.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/swinv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..3bc420a292ad7bfd80791aafa6f4ecb40bdd4242
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/swinv2.md
@@ -0,0 +1,63 @@
+
+
+# Swin Transformer V2 [[swin-transformer-v2]]
+
+## 개요 [[overview]]
+
+Swin Transformer V2는 Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo가 제안한 논문 [Swin Transformer V2: Scaling Up Capacity and Resolution](https://arxiv.org/abs/2111.09883)에서 소개되었습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*대규모 NLP 모델들은 언어 작업에서의 성능을 크게 향상하며, 성능이 포화하는 징후를 보이지 않습니다. 또한, 사람과 유사한 few-shot 학습 능력을 보여줍니다. 이 논문은 대규모 모델을 컴퓨터 비전 분야에서 탐구하고자 합니다. 대형 비전 모델을 훈련하고 적용하는 데 있어 세 가지 주요 문제를 다룹니다: 훈련 불안정성, 사전 학습과 파인튜닝 간의 해상도 차이, 그리고 레이블이 달린 데이터에 대한 높은 요구입니다. 세 가지 주요 기법을 제안합니다: 1) 훈련 안정성을 개선하기 위한 residual-post-norm 방법과 cosine attention의 결합; 2) 저해상도 이미지로 사전 학습된 모델을 고해상도 입력으로 전이할 수 있는 log-spaced continuous position bias 방법; 3) 레이블이 달린 방대한 이미지의 필요성을 줄이기 위한 self-supervised 사전 학습 방법인 SimMIM입니다. 이러한 기법들을 통해 30억 개의 파라미터를 가진 Swin Transformer V2 모델을 성공적으로 훈련하였으며, 이는 현재까지 가장 크고 고밀도의 비전 모델로, 최대 1,536×1,536 해상도의 이미지를 다룰 수 있습니다. 이 모델은 ImageNet-V2 이미지 분류, COCO 객체 탐지, ADE20K 의미론적 분할, Kinetics-400 비디오 행동 분류 등 네 가지 대표적인 비전 작업에서 새로운 성능 기록을 세웠습니다. 또한, 우리의 훈련은 Google의 billion-level 비전 모델과 비교해 40배 적은 레이블이 달린 데이터와 40배 적은 훈련 시간으로 이루어졌다는 점에서 훨씬 더 효율적입니다.*
+
+이 모델은 [nandwalritik](https://huggingface.co/nandwalritik)이 기여하였습니다.
+원본 코드는 [여기](https://github.com/microsoft/Swin-Transformer)에서 확인할 수 있습니다.
+
+## 리소스 [[resources]]
+
+Swin Transformer v2의 사용을 도울 수 있는 Hugging Face 및 커뮤니티(🌎로 표시)의 공식 자료 목록입니다.
+
+
+
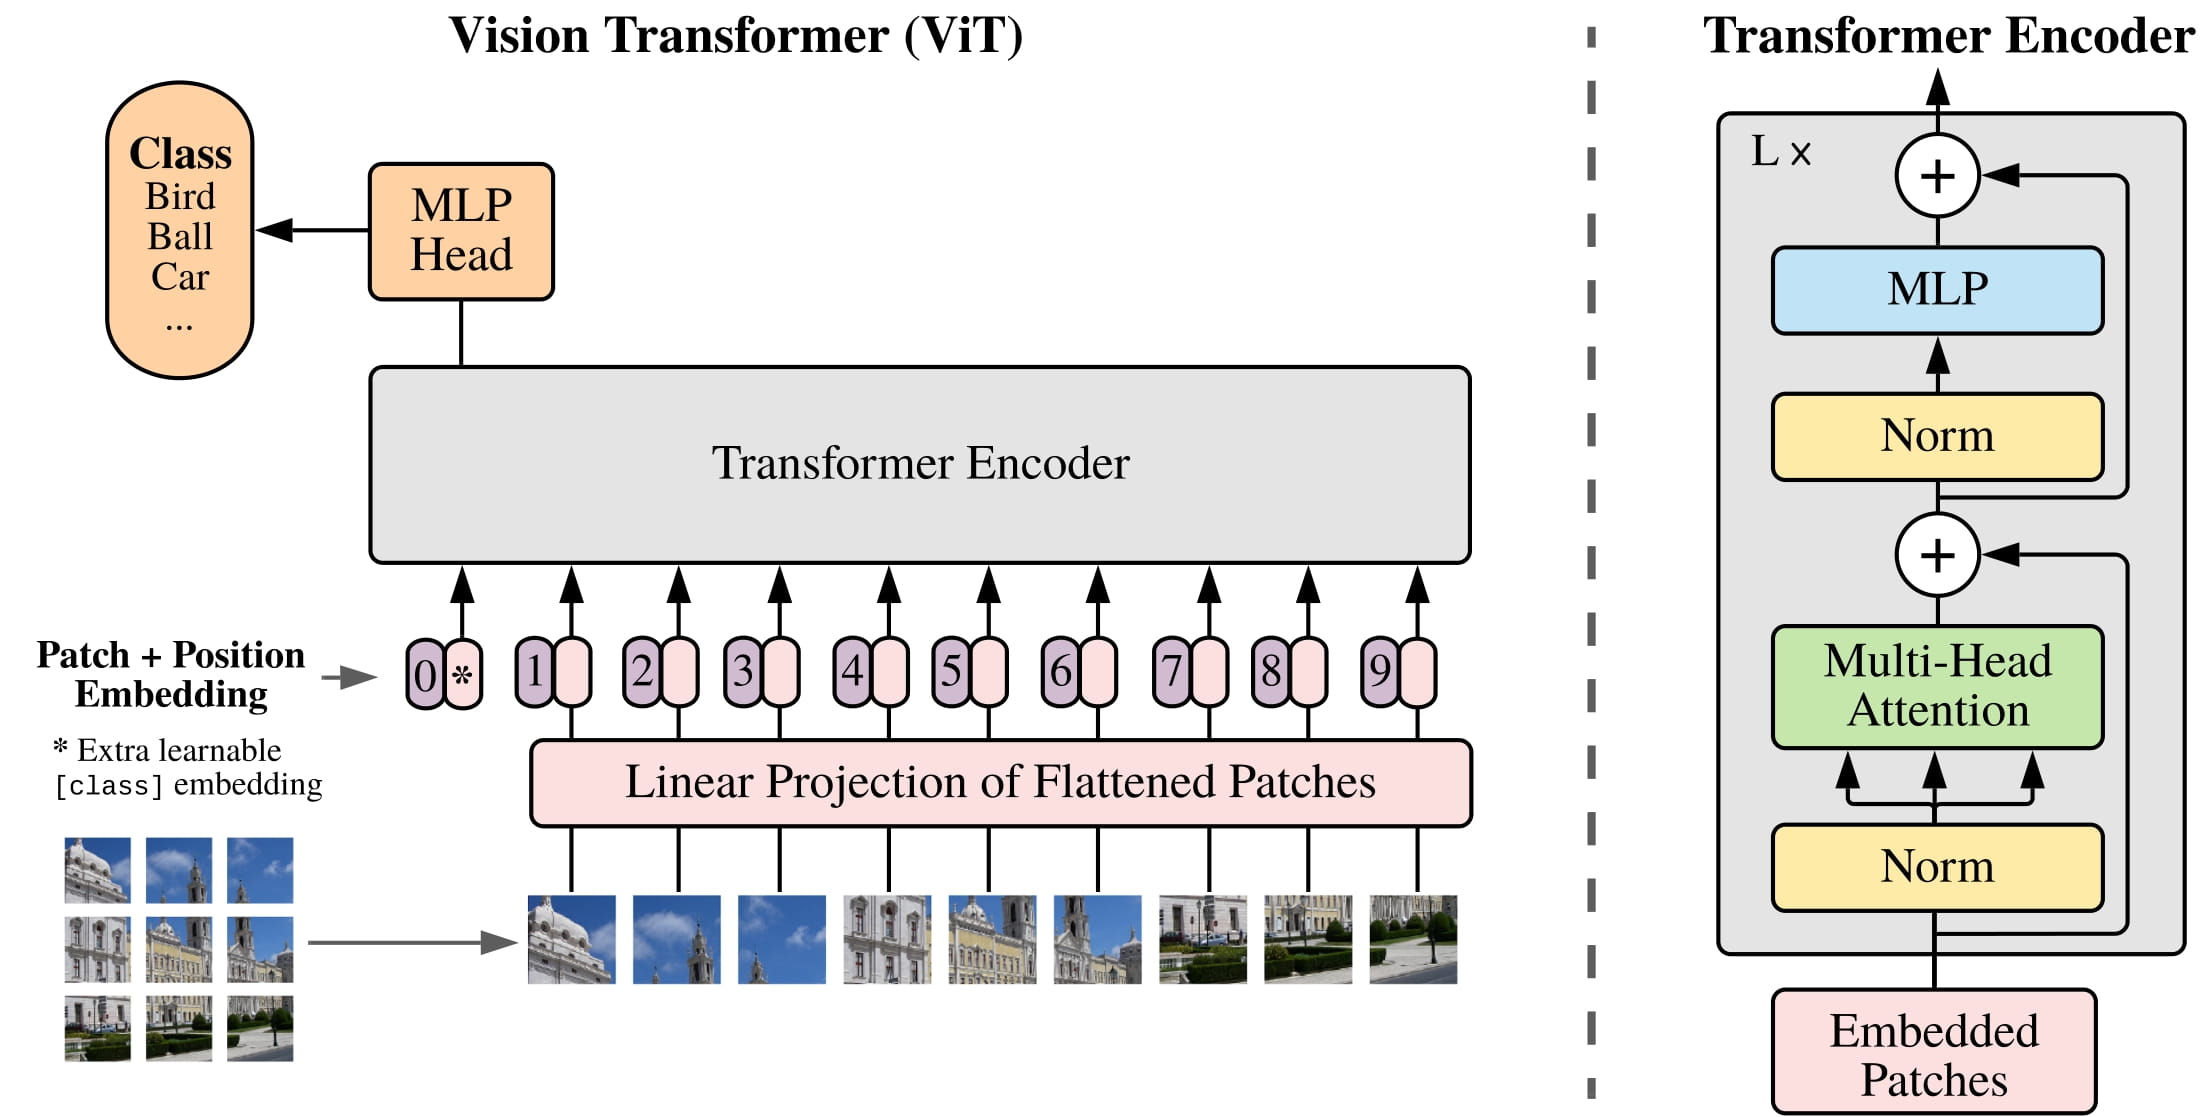 +
+ ViT 아키텍처. 원본 논문에서 발췌.
+
+원래의 Vision Transformer에 이어, 여러 후속 연구들이 진행되었습니다:
+
+
+- [DeiT](deit) (Data-efficient Image Transformers) (Facebook AI 개발). DeiT 모델은 distilled vision transformers입니다.
+ DeiT의 저자들은 더 효율적으로 훈련된 ViT 모델도 공개했으며, 이는 [`ViTModel`] 또는 [`ViTForImageClassification`]에 바로 사용할 수 있습니다. 여기에는 3가지 크기로 4개의 변형이 제공됩니다: *facebook/deit-tiny-patch16-224*, *facebook/deit-small-patch16-224*, *facebook/deit-base-patch16-224* and *facebook/deit-base-patch16-384*. 그리고 모델에 이미지를 준비하려면 [`DeiTImageProcessor`]를 사용해야 한다는 점에 유의하십시오.
+
+- [BEiT](beit) (BERT pre-training of Image Transformers) (Microsoft Research 개발). BEiT 모델은 BERT (masked image modeling)에 영감을 받고 VQ-VAE에 기반한 self-supervised 방법을 이용하여 supervised pre-trained vision transformers보다 더 우수한 성능을 보입니다.
+
+- DINO (Vision Transformers의 self-supervised 훈련을 위한 방법) (Facebook AI 개발). DINO 방법으로 훈련된 Vision Transformer는 학습되지 않은 상태에서도 객체를 분할할 수 있는 합성곱 신경망에서는 볼 수 없는 매우 흥미로운 능력을 보여줍니다. DINO 체크포인트는 [hub](https://huggingface.co/models?other=dino)에서 찾을 수 있습니다.
+
+- [MAE](vit_mae) (Masked Autoencoders) (Facebook AI 개발). Vision Transformer를 비대칭 인코더-디코더 아키텍처를 사용하여 마스크된 패치의 높은 비율(75%)에서 픽셀 값을 재구성하도록 사전 학습함으로써, 저자들은 이 간단한 방법이 미세 조정 후 supervised 방식의 사전 학습을 능가한다는 것을 보여주었습니다.
+
+이 모델은 [nielsr](https://huggingface.co/nielsr)에 의해 기여되었습니다. 원본 코드(JAX로 작성됨)은 [여기](https://github.com/google-research/vision_transformer)에서 확인할 수 있습니다.
+
+
+참고로, 우리는 Ross Wightman의 [timm 라이브러리](https://github.com/rwightman/pytorch-image-models)에서 JAX에서 PyTorch로 변환된 가중치를 다시 변환했습니다. 모든 공로는 그에게 돌립니다!
+
+## 사용 팁 [[usage-tips]]
+
+- Transformer 인코더에 이미지를 입력하기 위해, 각 이미지는 고정 크기의 겹치지 않는 패치들로 분할된 후 선형 임베딩됩니다. 전체 이미지를 대표하는 [CLS] 토큰이 추가되어, 분류에 사용할 수 있습니다. 저자들은 또한 절대 위치 임베딩을 추가하여, 결과적으로 생성된 벡터 시퀀스를 표준 Transformer 인코더에 입력합니다.
+- Vision Transformer는 모든 이미지가 동일한 크기(해상도)여야 하므로, [ViTImageProcessor]를 사용하여 이미지를 모델에 맞게 리사이즈(또는 리스케일)하고 정규화할 수 있습니다.
+- 사전 학습이나 미세 조정 시 사용된 패치 해상도와 이미지 해상도는 각 체크포인트의 이름에 반영됩니다. 예를 들어, `google/vit-base-patch16-224`는 패치 해상도가 16x16이고 미세 조정 해상도가 224x224인 기본 크기 아키텍처를 나타냅니다. 모든 체크포인트는 [hub](https://huggingface.co/models?search=vit)에서 확인할 수 있습니다.
+- 사용할 수 있는 체크포인트는 (1) [ImageNet-21k](http://www.image-net.org/) (1,400만 개의 이미지와 21,000개의 클래스)에서만 사전 학습되었거나, 또는 (2) [ImageNet](http://www.image-net.org/challenges/LSVRC/2012/) (ILSVRC 2012, 130만 개의 이미지와 1,000개의 클래스)에서 추가로 미세 조정된 경우입니다.
+- Vision Transformer는 224x224 해상도로 사전 학습되었습니다. 미세 조정 시, 사전 학습보다 더 높은 해상도를 사용하는 것이 유리한 경우가 많습니다 ([(Touvron et al., 2019)](https://arxiv.org/abs/1906.06423), [(Kolesnikovet al., 2020)](https://arxiv.org/abs/1912.11370). 더 높은 해상도로 미세 조정하기 위해, 저자들은 원본 이미지에서의 위치에 따라 사전 학습된 위치 임베딩의 2D 보간(interpolation)을 수행합니다.
+- 최고의 결과는 supervised 방식의 사전 학습에서 얻어졌으며, 이는 NLP에서는 해당되지 않는 경우가 많습니다. 저자들은 마스크된 패치 예측(마스크된 언어 모델링에서 영감을 받은 self-supervised 사전 학습 목표)을 사용한 실험도 수행했습니다. 이 접근 방식으로 더 작은 ViT-B/16 모델은 ImageNet에서 79.9%의 정확도를 달성하였으며, 이는 처음부터 학습한 것보다 2% 개선된 결과이지만, 여전히 supervised 사전 학습보다 4% 낮습니다.
+
+### Scaled Dot Product Attention (SDPA) 사용하기 [[using-scaled-dot-product-attention-sdpa]]
+
+PyTorch는 `torch.nn.functional`의 일부로서 native scaled dot-product attention (SDPA) 연산자를 포함하고 있습니다. 이 함수는 입력 및 사용 중인 하드웨어에 따라 여러 구현 방식을 적용할 수 있습니다.자세한 내용은 [공식 문서](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)나 [GPU 추론](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention) 페이지를 참조하십시오.
+
+SDPA는 `torch>=2.1.1`에서 구현이 가능한 경우 기본적으로 사용되지만, `from_pretrained()`에서 `attn_implementation="sdpa"`로 설정하여 SDPA를 명시적으로 요청할 수도 있습니다.
+
+```
+from transformers import ViTForImageClassification
+model = ViTForImageClassification.from_pretrained("google/vit-base-patch16-224", attn_implementation="sdpa", torch_dtype=torch.float16)
+...
+```
+
+최적의 속도 향상을 위해 모델을 반정밀도(예: `torch.float16` 또는 `torch.bfloat16`)로 로드하는 것을 권장합니다.
+
+로컬 벤치마크(A100-40GB, PyTorch 2.3.0, OS Ubuntu 22.04)에서 `float32`와 `google/vit-base-patch16-224` 모델을 사용한 추론 시, 다음과 같은 속도 향상을 확인했습니다.
+
+| Batch size | Average inference time (ms), eager mode | Average inference time (ms), sdpa model | Speed up, Sdpa / Eager (x) |
+|--------------|-------------------------------------------|-------------------------------------------|------------------------------|
+| 1 | 7 | 6 | 1.17 |
+| 2 | 8 | 6 | 1.33 |
+| 4 | 8 | 6 | 1.33 |
+| 8 | 8 | 6 | 1.33 |
+
+## 리소스 [[resources]]
+
+ViT의 추론 및 커스텀 데이터에 대한 미세 조정과 관련된 데모 노트북은 [여기](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/VisionTransformer)에서 확인할 수 있습니다. Hugging Face에서 공식적으로 제공하는 자료와 커뮤니티(🌎로 표시된) 자료 목록은 ViT를 시작하는 데 도움이 될 것입니다. 이 목록에 포함될 자료를 제출하고 싶다면 Pull Request를 열어 주시면 검토하겠습니다. 새로운 내용을 설명하는 자료가 가장 이상적이며, 기존 자료를 중복하지 않도록 해주십시오.
+
+`ViTForImageClassification` 은 다음에서 지원됩니다:
+
 +
+이는 시퀀스 확률의 실제 분해에 더 가까운 근사치이며 일반적으로 더 유리한 점수를 산출합니다.
+단점은 말뭉치의 각 토큰에 대해 별도의 포워드 패스가 필요하다는 것입니다.
+현실적으로 좋은 절충안은 한 번에 한 토큰씩 슬라이딩하는 것이 아니라 더 큰 간격으로 컨텍스트를 이동하는 스트라이드가 적용된 슬라이딩 윈도우을 사용하는 것입니다.
+이렇게 하면 계산을 훨씬 더 빠르게 진행하면서도 모델에 각 단계에서 예측을 수행할 수 있는 긴 컨텍스트를 제공할 수 있습니다.
+
+## 예제: 🤗 Transformers에서 GPT-2로 펄플렉서티(perplexity) 계산하기[[example-calculating-perplexity-with-gpt2-in-transformers]]
+
+이제 GPT-2로 위의 과정을 시연해 보겠습니다.
+
+```python
+from transformers import GPT2LMHeadModel, GPT2TokenizerFast
+
+device = "cuda"
+model_id = "openai-community/gpt2-large"
+model = GPT2LMHeadModel.from_pretrained(model_id).to(device)
+tokenizer = GPT2TokenizerFast.from_pretrained(model_id)
+```
+
+WikiText-2 데이터 세트를 가져오고 몇 가지 슬라이딩 윈도우 전략을 사용해 펄플렉서티를 계산해보겠습니다.
+이 데이터 세트는 크기가 작고 포워드 패스 한 번만 수행하기 때문에 전체 데이터 세트를 메모리에 가져오고 인코딩할 수 있습니다.
+
+```python
+from datasets import load_dataset
+
+test = load_dataset("wikitext", "wikitext-2-raw-v1", split="test")
+encodings = tokenizer("\n\n".join(test["text"]), return_tensors="pt")
+```
+
+🤗 Transformers를 사용하면 모델의 `labels`로 `input_ids`를 전달해 각 토큰에 대한 평균 음의 우도 값을 손실로 반환할 수 있습니다.
+하지만 슬라이딩 윈도우 방식을 사용하면 각 반복마다 모델에 전달하는 토큰이 겹칩니다.
+컨텍스트로 처리하는 토큰에 대한 로그 우도 값이 손실에 포함되는 것을 원하지 않기 때문에 이러한 토큰의 `input_ids`를 `-100`으로 설정하여 무시할 수 있습니다.
+
+다음은 스트라이드(stride)를 `512`로 사용한 예시입니다.
+즉, 모델이 한 토큰의 조건부 우도 값을 계산할 때 컨텍스트에 최소한 512개의 토큰이 포함되어있다는 의미입니다 (해당 토큰 앞에 512개의 토큰이 있는 경우).
+
+```python
+import torch
+from tqdm import tqdm
+
+max_length = model.config.n_positions
+stride = 512
+seq_len = encodings.input_ids.size(1)
+
+nlls = []
+prev_end_loc = 0
+for begin_loc in tqdm(range(0, seq_len, stride)):
+ end_loc = min(begin_loc + max_length, seq_len)
+ trg_len = end_loc - prev_end_loc # 마지막 루프의 스트라이드 값과 다를 수 있음
+ input_ids = encodings.input_ids[:, begin_loc:end_loc].to(device)
+ target_ids = input_ids.clone()
+ target_ids[:, :-trg_len] = -100
+
+ with torch.no_grad():
+ outputs = model(input_ids, labels=target_ids)
+
+ # 손실은 모든 유효한 레이블에 대한 평균값을 구하는 교차 엔트로피(cross entropy)로 계산됩니다.
+ # 나이브 베이지안 모델은 내부적으로 레이블을 왼쪽으로 1개씩 밀기 때문에, (타켓 - 1)개 만큼의 레이블에 대해 손실을 계산합니다.
+ neg_log_likelihood = outputs.loss
+
+ nlls.append(neg_log_likelihood)
+
+ prev_end_loc = end_loc
+ if end_loc == seq_len:
+ break
+
+ppl = torch.exp(torch.stack(nlls).mean())
+```
+
+스트라이드를 최대 입력 길이와 동일하게 설정하면 위에서 설명한 차선책인 비슬라이딩 윈도우 전략과 동일합니다.
+일반적으로 스트라이드가 작을수록 모델이 각 예측을 할 때 더 많은 컨텍스트를 볼 수 있게 되어 펄플렉서티 값이 좋아집니다.
+
+위의 계산을 토큰이 겹치지 않도록 `stride = 1024`로 설정하면 PPL은 `19.44`로 GPT-2 논문에서 보고된 `19.93`과 거의 동일합니다.
+`stride = 512`로 슬라이딩 윈도우 전략을 사용하면 PPL은 `16.45`로 떨어집니다.
+이는 더 좋은 점수일 뿐만 아니라 시퀀스 확률의 실제 자동 회귀 분해에 더 가까운 방식으로 계산됩니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/philosophy.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/philosophy.md
new file mode 100644
index 0000000000000000000000000000000000000000..e303709a11b8336a3cae1f6a6c5321ef953c4bc9
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/philosophy.md
@@ -0,0 +1,66 @@
+
+
+# 이념과 목표 [[philosophy]]
+
+🤗 Transformers는 다음과 같은 목적으로 만들어진 독자적인 라이브러리입니다:
+
+- 대규모 Transformers 모델을 사용하거나 연구하거나 확장하려는 기계 학습 연구원 및 교육자를 위한 것입니다.
+- 모델을 미세 조정하거나 제작용으로 사용하고자 하는 실전 개발자를 위한 것입니다.
+- 특정 기계 학습 작업을 해결하기 위해 사전훈련된 모델을 다운로드하고 사용하기만 하려는 엔지니어를 위한 것입니다.
+
+이 라이브러리는 두 가지 주요 목표를 가지고 설계되었습니다:
+
+1. 사용하기 쉽고 빠르게 만드는 것:
+
+- 학습해야 할 사용자 대상 추상화의 수를 제한했습니다. 실제로 거의 추상화가 없으며, 각 모델을 사용하기 위해 필요한 세 가지 표준 클래스인 [configuration](main_classes/configuration), [models](main_classes/model) 및 전처리 클래스인 ([tokenizer](main_classes/tokenizer)는 NLP용, [image processor](main_classes/image_processor)는 비전용, [feature extractor](main_classes/feature_extractor)는 오디오용, [processor](main_classes/processors)는 멀티모달 입력용)만 사용합니다.
+- 이러한 클래스는 공통적인 `from_pretrained()` 메서드를 사용하여 미리 훈련된 인스턴스에서 간단하고 통일된 방식으로 초기화할 수 있습니다. 이 메소드는 미리 훈련된 체크포인트에서 관련 클래스 인스턴스와 관련 데이터(구성의 하이퍼파라미터, 토크나이저의 어휘, 모델의 가중치)를 (필요한 경우) 다운로드하고 캐시하며 가져옵니다. 체크포인트는 [Hugging Face Hub](https://huggingface.co/models)에서 제공되거나 사용자 자체의 저장된 체크포인트에서 제공됩니다.
+- 이 세 가지 기본 클래스 위에 라이브러리는 [`pipeline`] API를 제공하여 주어진 작업에 대해 모델을 빠르게 추론하는 데 사용하고, [`Trainer`]를 제공하여 PyTorch 모델을 빠르게 훈련하거나 미세 조정할 수 있도록 합니다(모든 TensorFlow 모델은 `Keras.fit`과 호환됩니다).
+- 결과적으로, 이 라이브러리는 신경망을 구축하기 위한 모듈식 도구 상자가 아닙니다. 라이브러리를 확장하거나 구축하려면 일반적인 Python, PyTorch, TensorFlow, Keras 모듈을 사용하고 라이브러리의 기본 클래스를 상속하여 모델 로딩 및 저장과 같은 기능을 재사용하면 됩니다. 모델에 대한 코딩 철학에 대해 더 자세히 알고 싶다면 [Repeat Yourself](https://huggingface.co/blog/transformers-design-philosophy) 블로그 글을 확인해보세요.
+
+2. 원래 모델과 가능한 한 근접한 성능을 제공하는 최신 모델을 제공하는 것:
+
+- 각 아키텍처에 대해 공식 저자가 제공한 결과를 재현하는 적어도 한 가지 예제를 제공합니다.
+- 코드는 원래 코드와 가능한 한 유사하게 유지되므로 PyTorch 코드는 TensorFlow 코드로 변환되어 *pytorchic*하지 않을 수 있고, 그 반대의 경우도 마찬가지입니다.
+
+기타 목표 몇 가지:
+
+- 모델의 내부를 가능한 일관되게 노출시키기:
+
+ - 전체 은닉 상태와 어텐션 가중치에 대한 액세스를 단일 API를 사용하여 제공합니다.
+ - 전처리 클래스 및 기본 모델 API는 모델 간에 쉽게 전환할 수 있도록 표준화되어 있습니다.
+
+- 미세 조정 및 모델 탐색을 위한 유망한 도구들을 주관적으로 선택하기:
+
+ - 미세 조정을 위해 어휘 및 임베딩에 새로운 토큰을 간단하고 일관된 방식으로 추가하는 방법을 제공합니다.
+ - Transformer 헤드를 마스킹하고 가지치기하는 간단한 방법을 제공합니다.
+
+- PyTorch, TensorFlow 2.0 및 Flax 간에 쉽게 전환할 수 있도록 하여 하나의 프레임워크로 훈련하고 다른 프레임워크로 추론할 수 있게 합니다.
+
+## 주요 개념 [[main-concepts]]
+
+이 라이브러리는 각 모델에 대해 세 가지 유형의 클래스를 기반으로 구축되었습니다:
+
+- **모델 클래스**는 라이브러리에서 제공하는 사전 훈련된 가중치와 함께 작동하는 PyTorch 모델([torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module)), Keras 모델([tf.keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model)), JAX/Flax 모델([flax.linen.Module](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html))일 수 있습니다.
+- **구성 클래스**는 모델을 구축하는 데 필요한 하이퍼파라미터(예: 레이어 수 및 은닉 크기)를 저장합니다. 구성 클래스를 직접 인스턴스화할 필요는 없습니다. 특히, 수정 없이 고 사전 학습된 모델을 사용하는 경우 모델을 생성하면 모델의 일부인 구성을 자동으로 인스턴스화됩니다.
+- **전처리 클래스**는 원시 데이터를 모델이 수용하는 형식으로 변환합니다. [Tokenizer](main_classes/tokenizer)는 각 모델의 어휘를 저장하고, 문자열을 토큰 임베딩 인덱스 리스트로 인코딩하고 디코딩하기 위한 메소드를 제공합니다. [Image processors](main_classes/image_processor)는 비전 입력을 전처리하고, [feature extractors](main_classes/feature_extractor)는 오디오 입력을 전처리하며, [processor](main_classes/processors)는 멀티모달 입력을 처리합니다.
+
+모든 이러한 클래스는 사전 훈련된 인스턴스에서 인스턴스화하고 로컬로 저장하며, 세 가지 메소드를 사용하여 Hub에서 공유할 수 있습니다:
+
+- `from_pretrained()` 메소드를 사용하면 라이브러리 자체에서 제공하는 사전 훈련된 버전(지원되는 모델은 [Model Hub](https://huggingface.co/models)에서 찾을 수 있음)이나 사용자가 로컬로 저장한 경우(또는 서버에 저장한 경우)의 모델, 구성 및 전처리 클래스를 인스턴스화할 수 있습니다.
+- `save_pretrained()` 메소드를 사용하면 모델, 구성 및 전처리 클래스를 로컬로 저장하여 `from_pretrained()`를 사용하여 다시 가져올 수 있습니다.
+- `push_to_hub()` 메소드를 사용하면 모델, 구성 및 전처리 클래스를 Hub에 공유하여 모두에게 쉽게 접근할 수 있습니다.
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/pipeline_tutorial.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/pipeline_tutorial.md
new file mode 100644
index 0000000000000000000000000000000000000000..2f166fc6939f3206f3b03490c140a5c3f360045f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/pipeline_tutorial.md
@@ -0,0 +1,243 @@
+
+
+# 추론을 위한 Pipeline[[pipelines-for-inference]]
+
+[`pipeline`]을 사용하면 언어, 컴퓨터 비전, 오디오 및 멀티모달 태스크에 대한 추론을 위해 [Hub](https://huggingface.co/models)의 어떤 모델이든 쉽게 사용할 수 있습니다. 특정 분야에 대한 경험이 없거나, 모델을 이루는 코드가 익숙하지 않은 경우에도 [`pipeline`]을 사용해서 추론할 수 있어요! 이 튜토리얼에서는 다음을 배워보겠습니다.
+
+* 추론을 위해 [`pipeline`]을 사용하는 방법
+* 특정 토크나이저 또는 모델을 사용하는 방법
+* 언어, 컴퓨터 비전, 오디오 및 멀티모달 태스크에서 [`pipeline`]을 사용하는 방법
+
+
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
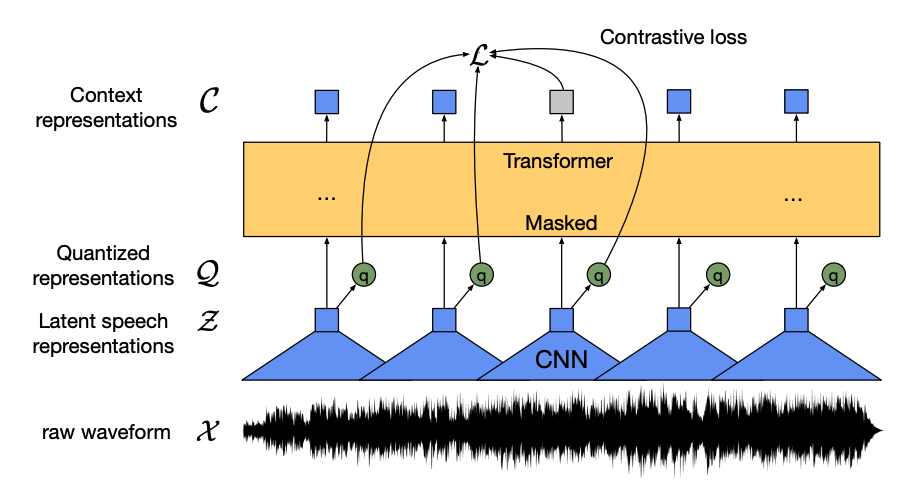 +
 +
 +
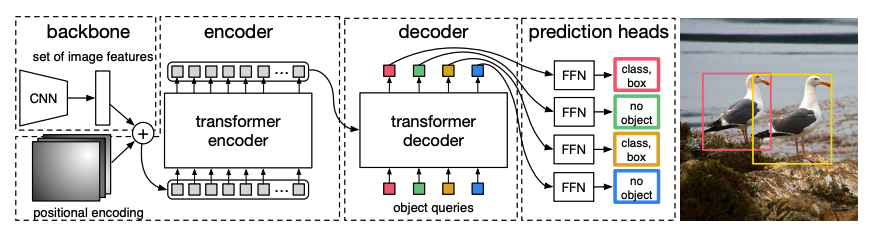 +
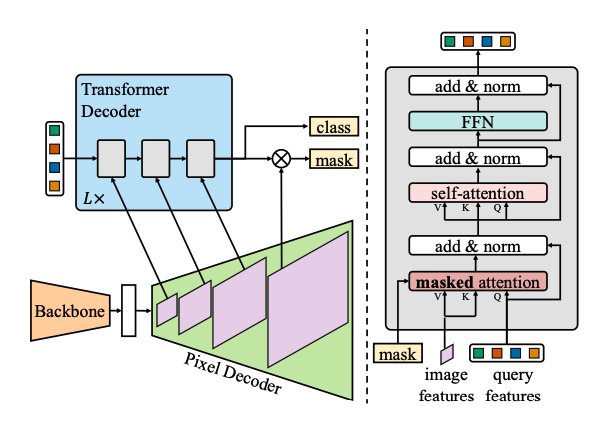 +
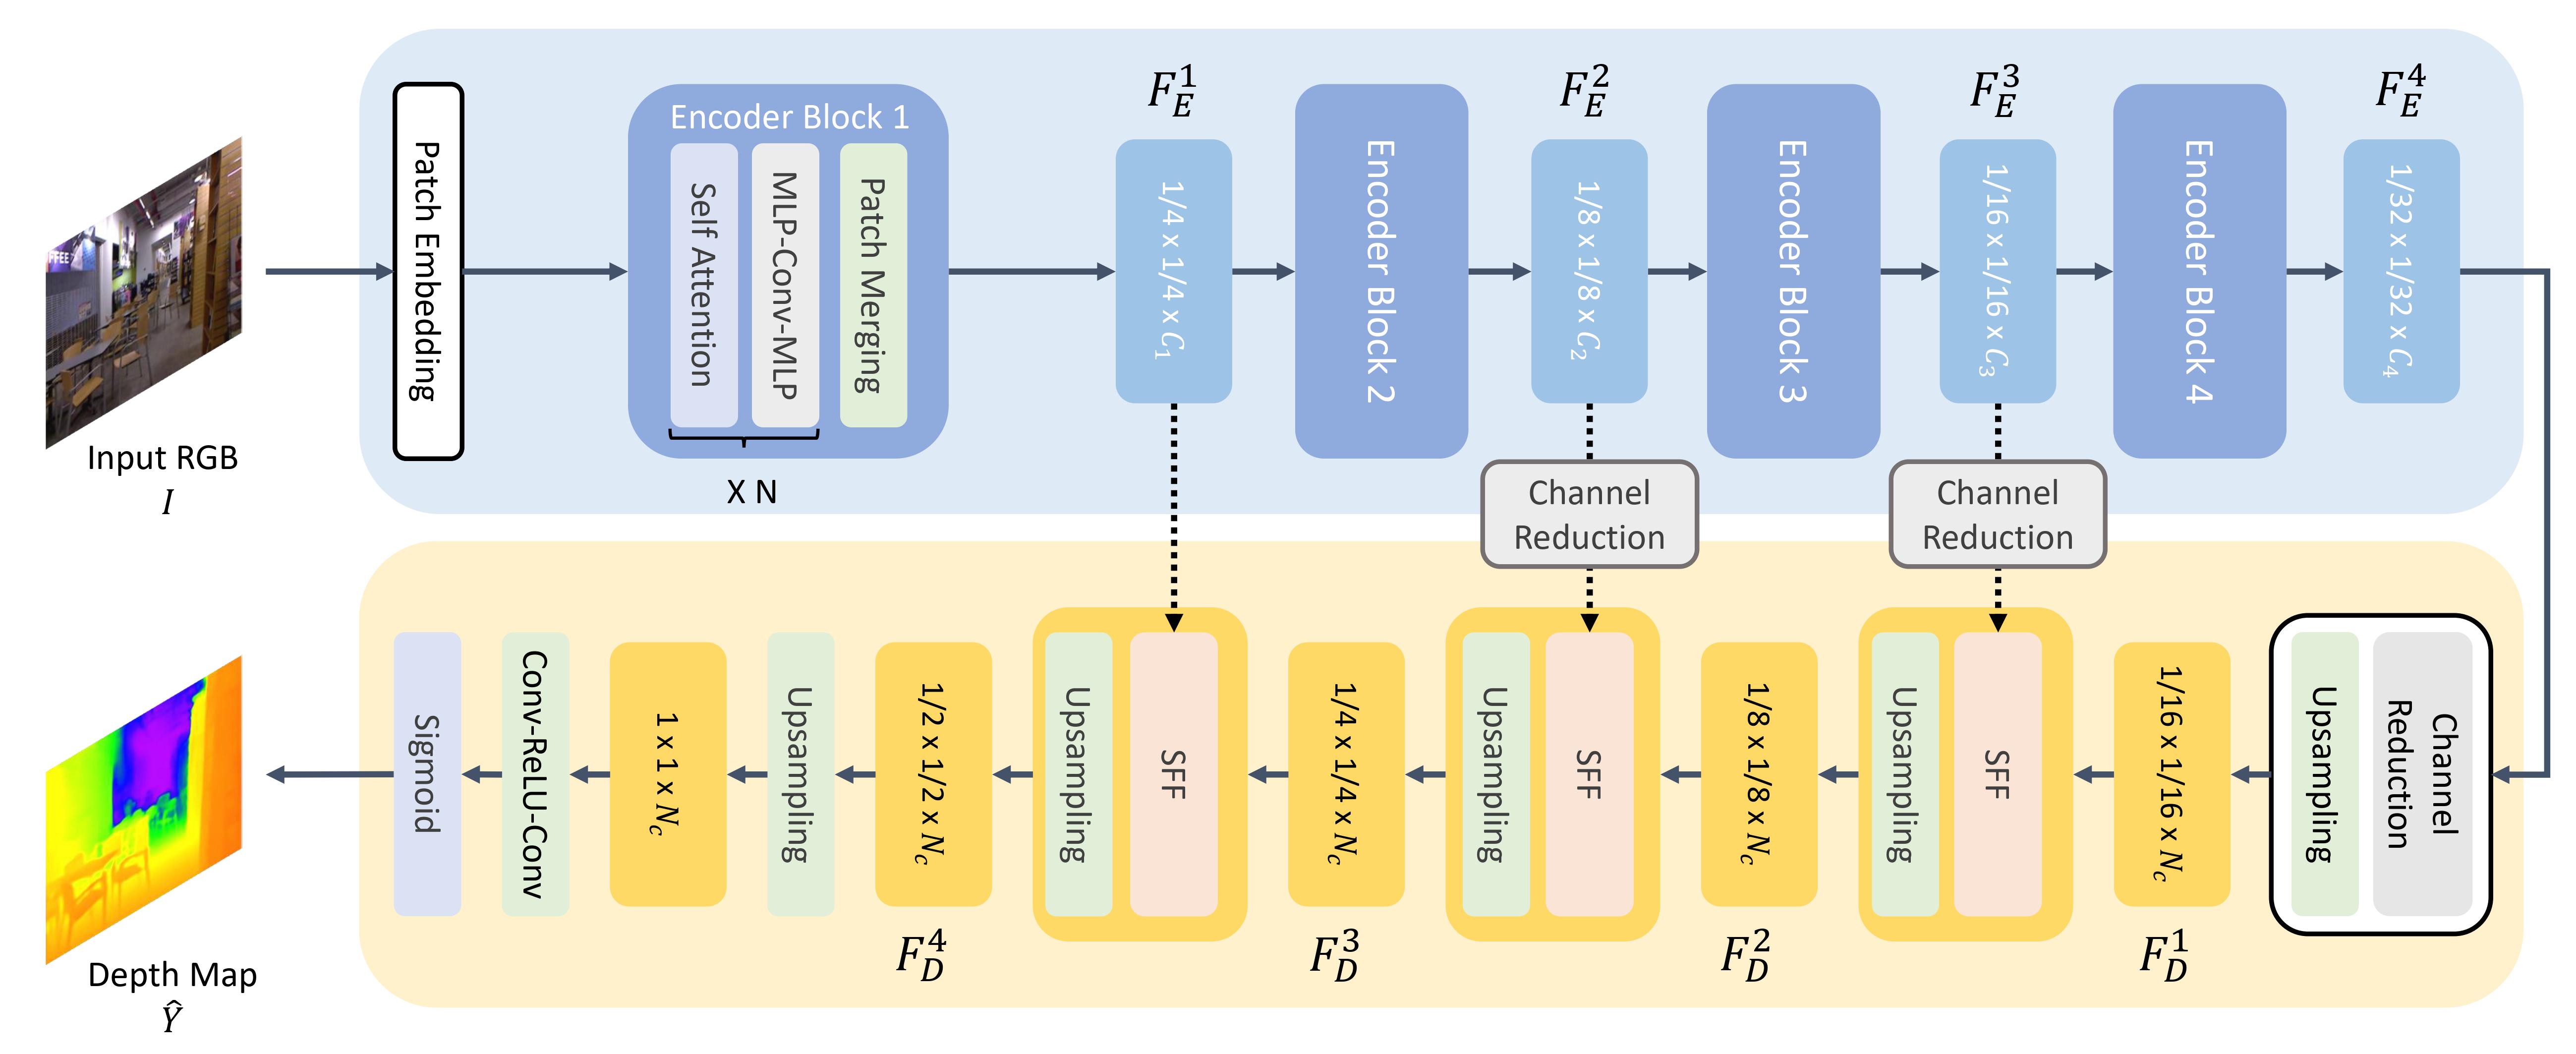 +
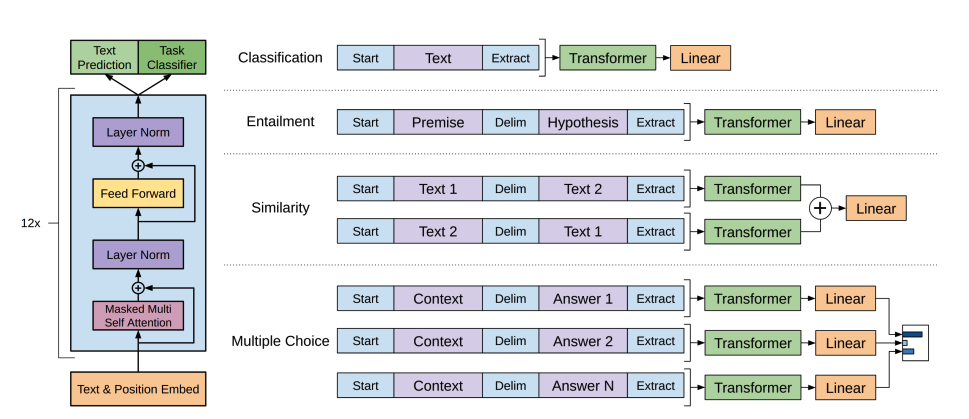 +
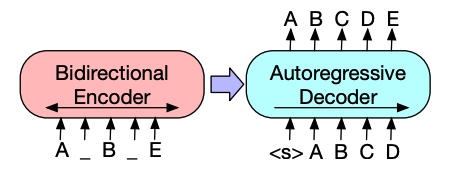 +
 | A beaver is swimming in the water |
+
+---
+
+```py
+agent.run("Read the following text out loud", text=text)
+```
+| **Input** | **Output** |
+|-------------------------------------------------------------------------------------------------------------------------|----------------------------------------------|
+| A beaver is swimming in the water |
+
+---
+
+```py
+agent.run(
+ "In the following `document`, where will the TRRF Scientific Advisory Council Meeting take place?",
+ document=document,
+)
+```
+| **Input** | **Output** |
+|-----------------------------------------------------------------------------------------------------------------------------|----------------|
+|
 | ballroom foyer |
+
+## 바로 시작하기 [[quickstart]]
+
+`agent.run`을 사용하려면 먼저 대규모 언어 모델(LLM)인 에이전트를 인스턴스화해야 합니다.
+저희는 openAI 모델뿐만 아니라 BigCode 및 OpenAssistant의 오픈소스 대체 모델도 지원합니다.
+openAI 모델의 성능이 더 우수하지만(단, openAI API 키가 필요하므로 무료로 사용할 수 없음),
+Hugging Face는 BigCode와 OpenAssistant 모델의 엔드포인트에 대한 무료 액세스를 제공하고 있습니다.
+
+우선 모든 기본 종속성을 설치하려면 `agents`를 추가로 설치하세요.
+```bash
+pip install transformers[agents]
+```
+
+openAI 모델을 사용하려면 `openai` 종속성을 설치한 후 [`OpenAiAgent`]를 인스턴스화합니다:
+
+```bash
+pip install openai
+```
+
+
+```py
+from transformers import OpenAiAgent
+
+agent = OpenAiAgent(model="text-davinci-003", api_key="
 +
+수행하려는 작업에 적합한 도구를 자동으로 선택하여 적절하게 실행합니다.
+동일한 명령어에서 하나 또는 여러 개의 작업을 수행할 수 있습니다
+(다만, 명령어가 복잡할수록 에이전트가 실패할 가능성이 높아집니다).
+
+```py
+agent.run("Draw me a picture of the sea then transform the picture to add an island")
+```
+
+
 +
+
 +
+
 +
+#### 에이전트 [[agents]]
+
+여기서 "에이전트"는 대규모 언어 모델이며, 특정 도구 모음에 접근할 수 있도록 프롬프트하고 있습니다.
+
+LLM은 작은 코드 샘플을 생성하는 데 상당히 능숙하므로,
+이 장점을 활용해 도구 모음을 사용하여 작업을 수행하는 작은 코드 샘플을 제공하라는 메시지를 표시합니다.
+그런 다음 에이전트에게 제공하는 작업과 제공하는 도구에 대한 설명으로 이 프롬프트가 완료됩니다.
+이렇게 하면 사용 중인 도구들의 문서에 접근할 수 있으며, 해당 도구들의 입력과 출력을 예상하고, 관련된 코드를 생성할 수 있습니다.
+
+#### 도구 [[tools]]
+
+도구는 매우 간단합니다. 이름과 설명이 있는 단일 기능으로 구성되어 있습니다.
+그런 다음 이러한 도구의 설명을 사용하여 상담원에게 프롬프트를 표시합니다.
+이 프롬프트를 통해 상담원에게 쿼리에서 요청된 작업을 수행하기 위해 도구를 활용하는 방법을 보여줍니다.
+
+에이전트가 매우 원자적인 도구를 사용하여 더 나은 코드를 작성하기 때문에 파이프라인이 아닌 완전히 새로운 도구를 사용합니다.
+파이프라인은 더 많이 리팩터링되며 종종 여러 작업을 하나로 결합합니다.
+도구는 하나의 매우 간단한 작업에만 집중하도록 되어 있습니다.
+
+#### 코드 실행?! [[code-execution]]
+
+그런 다음 이 코드는 도구와 함께 전달된 입력 세트에 대해 작은 Python 인터프리터를 사용하여 실행됩니다.
+"임의 코드 실행이라니!"이라고 비명을 지르는 소리가 들리겠지만, 그렇지 않은 이유를 설명하겠습니다.
+
+호출할 수 있는 함수는 제공한 도구와 인쇄 기능뿐이므로 이미 실행할 수 있는 기능이 제한되어 있습니다.
+Hugging Face 도구로 제한되어 있다면 안전할 것입니다.
+
+그리고 어트리뷰트 조회나 가져오기를 허용하지 않으므로
+(어차피 작은 함수 집합에 입/출력을 전달할 때는 필요하지 않아야 합니다)
+가장 명백한 공격(어차피 LLM에 출력하라는 메시지를 표시해야 합니다)은 문제가 되지 않습니다.
+매우 안전하게 하고 싶다면 추가 인수 return_code=True를 사용하여 run() 메소드를 실행하면 됩니다.
+이 경우 에이전트가 실행할 코드를 반환하고 실행할지 여부를 결정할 수 있습니다.
+
+불법적인 연산을 수행하려고 하거나 에이전트가 생성한 코드에 일반적인 파이썬 오류가 있는 경우
+실행이 중지됩니다.
+
+### 엄선된 도구 모음 [[a-curated-set-of-tools]]
+
+저희는 이러한 에이전트들의 역량을 강화할 수 있는 일련의 도구를 확인하고 있습니다.
+다음은 연동된 도구의 최신 목록입니다:
+
+- **문서 질문 답변**: 이미지 형식의 문서(예: PDF)가 주어지면 이 문서에 대한 질문에 답변합니다. ([Donut](./model_doc/donut))
+- **텍스트 질문 답변**: 긴 텍스트와 질문이 주어지면 텍스트에서 질문에 답변합니다. ([Flan-T5](./model_doc/flan-t5))
+- **무조건 이미지 캡셔닝**: 이미지에 캡션을 답니다! ([BLIP](./model_doc/blip))
+- **이미지 질문 답변**: 이미지가 주어지면 이 이미지에 대한 질문에 답변하기. ([VILT](./model_doc/vilt))
+- **이미지 분할**: 이미지와 프롬프트가 주어지면 해당 프롬프트의 분할 마스크를 출력합니다. ([CLIPSeg](./model_doc/clipseg))
+- **음성을 텍스트로 변환**: 사람이 말하는 오디오 녹음이 주어지면 음성을 텍스트로 변환합니다. ([Whisper](./model_doc/whisper))
+- **텍스트 음성 변환**: 텍스트를 음성으로 변환합니다. ([SpeechT5](./model_doc/speecht5))
+- **제로 샷(zero-shot) 텍스트 분류**: 텍스트와 레이블 목록이 주어지면 텍스트와 가장 관련 있는 레이블을 식별합니다. ([BART](./model_doc/bart))
+- **텍스트 요약**: 긴 텍스트를 한 문장 또는 몇 문장으로 요약합니다. ([BART](./model_doc/bart))
+- **번역**: 텍스트를 지정된 언어로 번역합니다. ([NLLB](./model_doc/nllb))
+
+이러한 도구는 트랜스포머에 통합되어 있으며, 예를 들어 수동으로도 사용할 수 있습니다:
+
+```py
+from transformers import load_tool
+
+tool = load_tool("text-to-speech")
+audio = tool("This is a text to speech tool")
+```
+
+### 사용자 정의 도구 [[custom-tools]]
+
+엄선된 도구 세트도 있지만, 이 구현이 제공하는 가장 큰 가치는 사용자 지정 도구를 빠르게 만들고 공유할 수 있다는 점입니다.
+
+도구의 코드를 Hugging Face Space나 모델 저장소에 푸시하면 에이전트에게 직접 도구를 활용할 수 있습니다. [`huggingface-tools` organization](https://huggingface.co/huggingface-tools)에 몇 가지 **트랜스포머에 구애받지 않는** 툴을 추가했습니다:
+
+- **텍스트 다운로더**: 웹 URL에서 텍스트를 다운로드합니다.
+- **텍스트 이미지 변환**: 프롬프트에 따라 이미지를 생성하여 안정적인 확산을 활용합니다.
+- **이미지 변환**: 초기 이미지와 프롬프트가 주어진 이미지를 수정하고, 안정적인 확산을 활용하는 지시 픽셀 2 픽셀을 활용합니다.
+- **텍스트 비디오 변환**: 프롬프트에 따라 작은 비디오를 생성하며, damo-vilab을 활용합니다.
+
+저희가 처음부터 사용하고 있는 텍스트-이미지 변환 도구는 [*huggingface-tools/text-to-image*](https://huggingface.co/spaces/huggingface-tools/text-to-image)에 있는 원격 도구입니다! 저희는 이 도구와 다른 조직에 이러한 도구를 계속 출시하여 이 구현을 더욱 강화할 것입니다.
+
+에이전트는 기본적으로 [`huggingface-tools`](https://huggingface.co/huggingface-tools)에 있는 도구에 접근할 수 있습니다.
+[다음 가이드](custom_tools)에서 도구를 작성하고 공유하는 방법과 Hub에 있는 사용자 지정 도구를 활용하는 방법에 대해 설명합니다.
+
+### 코드 생성[[code-generation]]
+
+지금까지 에이전트를 사용하여 작업을 수행하는 방법을 보여드렸습니다. 하지만 에이전트는 매우 제한된 Python 인터프리터를 사용하여 실행할 코드만 생성하고 있습니다. 다른 설정에서 생성된 코드를 사용하려는 경우 에이전트에게 도구 정의 및 정확한 가져오기와 함께 코드를 반환하라는 메시지를 표시할 수 있습니다.
+
+예를 들어 다음 명령어는
+```python
+agent.run("Draw me a picture of rivers and lakes", return_code=True)
+```
+
+다음 코드를 반환합니다.
+
+```python
+from transformers import load_tool
+
+image_generator = load_tool("huggingface-tools/text-to-image")
+
+image = image_generator(prompt="rivers and lakes")
+```
+
+이 코드는 직접 수정하고 실행할 수 있습니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/troubleshooting.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/troubleshooting.md
new file mode 100644
index 0000000000000000000000000000000000000000..263d693c23da65f7a964ee64fdde70dff595ad2c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/troubleshooting.md
@@ -0,0 +1,198 @@
+
+
+# 문제 해결[[troubleshoot]]
+
+때때로 오류가 발생할 수 있지만, 저희가 도와드리겠습니다! 이 가이드는 현재까지 확인된 가장 일반적인 문제 몇 가지와 그것들을 해결하는 방법에 대해 다룹니다. 그러나 이 가이드는 모든 🤗 Transformers 문제를 포괄적으로 다루고 있지 않습니다. 문제 해결에 더 많은 도움을 받으려면 다음을 시도해보세요:
+
+
 +
+
+## Kandungan
+
+Dokumentasi disusun kepada lima bahagian:
+
+- **MULAKAN** menyediakan lawatan pantas ke perpustakaan dan arahan pemasangan untuk bangun dan berjalan.
+- **TUTORIAL** ialah tempat yang bagus untuk bermula jika anda seorang pemula. Bahagian ini akan membantu anda memperoleh kemahiran asas yang anda perlukan untuk mula menggunakan perpustakaan.
+- **PANDUAN CARA-CARA** menunjukkan kepada anda cara untuk mencapai matlamat tertentu, seperti memperhalusi model terlatih untuk pemodelan bahasa atau cara menulis dan berkongsi model tersuai.
+- **PANDUAN KONSEP** menawarkan lebih banyak perbincangan dan penjelasan tentang konsep dan idea asas di sebalik model, tugasan dan falsafah reka bentuk 🤗 Transformers.
+- **API** menerangkan semua kelas dan fungsi:
+
+ - **KELAS UTAMA** memperincikan kelas yang paling penting seperti konfigurasi, model, tokenizer dan saluran paip.
+ - **MODEL** memperincikan kelas dan fungsi yang berkaitan dengan setiap model yang dilaksanakan dalam perpustakaan.
+ - **PEMBANTU DALAMAN** memperincikan kelas utiliti dan fungsi yang digunakan secara dalaman.
+
+### Model yang disokong
+
+
+
+1. **[ALBERT](model_doc/albert)** (from Google Research and the Toyota Technological Institute at Chicago) released with the paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://arxiv.org/abs/1909.11942), by Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
+1. **[ALIGN](model_doc/align)** (from Google Research) released with the paper [Scaling Up Visual and Vision-Language Representation Learning With Noisy Text Supervision](https://arxiv.org/abs/2102.05918) by Chao Jia, Yinfei Yang, Ye Xia, Yi-Ting Chen, Zarana Parekh, Hieu Pham, Quoc V. Le, Yunhsuan Sung, Zhen Li, Tom Duerig.
+1. **[AltCLIP](model_doc/altclip)** (from BAAI) released with the paper [AltCLIP: Altering the Language Encoder in CLIP for Extended Language Capabilities](https://arxiv.org/abs/2211.06679) by Chen, Zhongzhi and Liu, Guang and Zhang, Bo-Wen and Ye, Fulong and Yang, Qinghong and Wu, Ledell.
+1. **[Audio Spectrogram Transformer](model_doc/audio-spectrogram-transformer)** (from MIT) released with the paper [AST: Audio Spectrogram Transformer](https://arxiv.org/abs/2104.01778) by Yuan Gong, Yu-An Chung, James Glass.
+1. **[Autoformer](model_doc/autoformer)** (from Tsinghua University) released with the paper [Autoformer: Decomposition Transformers with Auto-Correlation for Long-Term Series Forecasting](https://arxiv.org/abs/2106.13008) by Haixu Wu, Jiehui Xu, Jianmin Wang, Mingsheng Long.
+1. **[BART](model_doc/bart)** (from Facebook) released with the paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://arxiv.org/abs/1910.13461) by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer.
+1. **[BARThez](model_doc/barthez)** (from École polytechnique) released with the paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321) by Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
+1. **[BARTpho](model_doc/bartpho)** (from VinAI Research) released with the paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701) by Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen.
+1. **[BEiT](model_doc/beit)** (from Microsoft) released with the paper [BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254) by Hangbo Bao, Li Dong, Furu Wei.
+1. **[BERT](model_doc/bert)** (from Google) released with the paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805) by Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova.
+1. **[BERT For Sequence Generation](model_doc/bert-generation)** (from Google) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[BERTweet](model_doc/bertweet)** (from VinAI Research) released with the paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) by Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen.
+1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BigBird-RoBERTa](model_doc/big_bird)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BioGpt](model_doc/biogpt)** (from Microsoft Research AI4Science) released with the paper [BioGPT: generative pre-trained transformer for biomedical text generation and mining](https://academic.oup.com/bib/advance-article/doi/10.1093/bib/bbac409/6713511?guestAccessKey=a66d9b5d-4f83-4017-bb52-405815c907b9) by Renqian Luo, Liai Sun, Yingce Xia, Tao Qin, Sheng Zhang, Hoifung Poon and Tie-Yan Liu.
+1. **[BiT](model_doc/bit)** (from Google AI) released with the paper [Big Transfer (BiT): General Visual Representation Learning](https://arxiv.org/abs/1912.11370) by Alexander Kolesnikov, Lucas Beyer, Xiaohua Zhai, Joan Puigcerver, Jessica Yung, Sylvain Gelly, Neil Houlsby.
+1. **[Blenderbot](model_doc/blenderbot)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BlenderbotSmall](model_doc/blenderbot-small)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BLIP](model_doc/blip)** (from Salesforce) released with the paper [BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation](https://arxiv.org/abs/2201.12086) by Junnan Li, Dongxu Li, Caiming Xiong, Steven Hoi.
+1. **[BLIP-2](model_doc/blip-2)** (from Salesforce) released with the paper [BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models](https://arxiv.org/abs/2301.12597) by Junnan Li, Dongxu Li, Silvio Savarese, Steven Hoi.
+1. **[BLOOM](model_doc/bloom)** (from BigScience workshop) released by the [BigScience Workshop](https://bigscience.huggingface.co/).
+1. **[BORT](model_doc/bort)** (from Alexa) released with the paper [Optimal Subarchitecture Extraction For BERT](https://arxiv.org/abs/2010.10499) by Adrian de Wynter and Daniel J. Perry.
+1. **[BridgeTower](model_doc/bridgetower)** (from Harbin Institute of Technology/Microsoft Research Asia/Intel Labs) released with the paper [BridgeTower: Building Bridges Between Encoders in Vision-Language Representation Learning](https://arxiv.org/abs/2206.08657) by Xiao Xu, Chenfei Wu, Shachar Rosenman, Vasudev Lal, Wanxiang Che, Nan Duan.
+1. **[Bros](model_doc/bros)** (from NAVER) released with the paper [BROS: A Pre-trained Language Model Focusing on Text and Layout for Better Key Information Extraction from Documents](https://arxiv.org/abs/2108.04539) by Teakgyu Hong, Donghyun Kim, Mingi Ji, Wonseok Hwang, Daehyun Nam, Sungrae Park.
+1. **[ByT5](model_doc/byt5)** (from Google Research) released with the paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://arxiv.org/abs/2105.13626) by Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
+1. **[CamemBERT](model_doc/camembert)** (from Inria/Facebook/Sorbonne) released with the paper [CamemBERT: a Tasty French Language Model](https://arxiv.org/abs/1911.03894) by Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot.
+1. **[CANINE](model_doc/canine)** (from Google Research) released with the paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://arxiv.org/abs/2103.06874) by Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
+1. **[Chinese-CLIP](model_doc/chinese_clip)** (from OFA-Sys) released with the paper [Chinese CLIP: Contrastive Vision-Language Pretraining in Chinese](https://arxiv.org/abs/2211.01335) by An Yang, Junshu Pan, Junyang Lin, Rui Men, Yichang Zhang, Jingren Zhou, Chang Zhou.
+1. **[CLAP](model_doc/clap)** (from LAION-AI) released with the paper [Large-scale Contrastive Language-Audio Pretraining with Feature Fusion and Keyword-to-Caption Augmentation](https://arxiv.org/abs/2211.06687) by Yusong Wu, Ke Chen, Tianyu Zhang, Yuchen Hui, Taylor Berg-Kirkpatrick, Shlomo Dubnov.
+1. **[CLIP](model_doc/clip)** (from OpenAI) released with the paper [Learning Transferable Visual Models From Natural Language Supervision](https://arxiv.org/abs/2103.00020) by Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
+1. **[CLIPSeg](model_doc/clipseg)** (from University of Göttingen) released with the paper [Image Segmentation Using Text and Image Prompts](https://arxiv.org/abs/2112.10003) by Timo Lüddecke and Alexander Ecker.
+1. **[CodeGen](model_doc/codegen)** (from Salesforce) released with the paper [A Conversational Paradigm for Program Synthesis](https://arxiv.org/abs/2203.13474) by Erik Nijkamp, Bo Pang, Hiroaki Hayashi, Lifu Tu, Huan Wang, Yingbo Zhou, Silvio Savarese, Caiming Xiong.
+1. **[Conditional DETR](model_doc/conditional_detr)** (from Microsoft Research Asia) released with the paper [Conditional DETR for Fast Training Convergence](https://arxiv.org/abs/2108.06152) by Depu Meng, Xiaokang Chen, Zejia Fan, Gang Zeng, Houqiang Li, Yuhui Yuan, Lei Sun, Jingdong Wang.
+1. **[ConvBERT](model_doc/convbert)** (from YituTech) released with the paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496) by Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
+1. **[ConvNeXT](model_doc/convnext)** (from Facebook AI) released with the paper [A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545) by Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
+1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://arxiv.org/abs/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
+1. **[CPM](model_doc/cpm)** (from Tsinghua University) released with the paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://arxiv.org/abs/2012.00413) by Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
+1. **[CPM-Ant](model_doc/cpmant)** (from OpenBMB) released by the [OpenBMB](https://www.openbmb.org/).
+1. **[CTRL](model_doc/ctrl)** (from Salesforce) released with the paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://arxiv.org/abs/1909.05858) by Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher.
+1. **[CvT](model_doc/cvt)** (from Microsoft) released with the paper [CvT: Introducing Convolutions to Vision Transformers](https://arxiv.org/abs/2103.15808) by Haiping Wu, Bin Xiao, Noel Codella, Mengchen Liu, Xiyang Dai, Lu Yuan, Lei Zhang.
+1. **[Data2Vec](model_doc/data2vec)** (from Facebook) released with the paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://arxiv.org/abs/2202.03555) by Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
+1. **[DeBERTa](model_doc/deberta)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[DeBERTa-v2](model_doc/deberta-v2)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[Decision Transformer](model_doc/decision_transformer)** (from Berkeley/Facebook/Google) released with the paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://arxiv.org/abs/2106.01345) by Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
+1. **[Deformable DETR](model_doc/deformable_detr)** (from SenseTime Research) released with the paper [Deformable DETR: Deformable Transformers for End-to-End Object Detection](https://arxiv.org/abs/2010.04159) by Xizhou Zhu, Weijie Su, Lewei Lu, Bin Li, Xiaogang Wang, Jifeng Dai.
+1. **[DeiT](model_doc/deit)** (from Facebook) released with the paper [Training data-efficient image transformers & distillation through attention](https://arxiv.org/abs/2012.12877) by Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
+1. **[DePlot](model_doc/deplot)** (from Google AI) released with the paper [DePlot: One-shot visual language reasoning by plot-to-table translation](https://arxiv.org/abs/2212.10505) by Fangyu Liu, Julian Martin Eisenschlos, Francesco Piccinno, Syrine Krichene, Chenxi Pang, Kenton Lee, Mandar Joshi, Wenhu Chen, Nigel Collier, Yasemin Altun.
+1. **[DETA](model_doc/deta)** (from The University of Texas at Austin) released with the paper [NMS Strikes Back](https://arxiv.org/abs/2212.06137) by Jeffrey Ouyang-Zhang, Jang Hyun Cho, Xingyi Zhou, Philipp Krähenbühl.
+1. **[DETR](model_doc/detr)** (from Facebook) released with the paper [End-to-End Object Detection with Transformers](https://arxiv.org/abs/2005.12872) by Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
+1. **[DialoGPT](model_doc/dialogpt)** (from Microsoft Research) released with the paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://arxiv.org/abs/1911.00536) by Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
+1. **[DiNAT](model_doc/dinat)** (from SHI Labs) released with the paper [Dilated Neighborhood Attention Transformer](https://arxiv.org/abs/2209.15001) by Ali Hassani and Humphrey Shi.
+1. **[DistilBERT](model_doc/distilbert)** (from HuggingFace), released together with the paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://arxiv.org/abs/1910.01108) by Victor Sanh, Lysandre Debut and Thomas Wolf. The same method has been applied to compress GPT2 into [DistilGPT2](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), RoBERTa into [DistilRoBERTa](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), Multilingual BERT into [DistilmBERT](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation) and a German version of DistilBERT.
+1. **[DiT](model_doc/dit)** (from Microsoft Research) released with the paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://arxiv.org/abs/2203.02378) by Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
+1. **[Donut](model_doc/donut)** (from NAVER), released together with the paper [OCR-free Document Understanding Transformer](https://arxiv.org/abs/2111.15664) by Geewook Kim, Teakgyu Hong, Moonbin Yim, Jeongyeon Nam, Jinyoung Park, Jinyeong Yim, Wonseok Hwang, Sangdoo Yun, Dongyoon Han, Seunghyun Park.
+1. **[DPR](model_doc/dpr)** (from Facebook) released with the paper [Dense Passage Retrieval for Open-Domain Question Answering](https://arxiv.org/abs/2004.04906) by Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih.
+1. **[DPT](master/model_doc/dpt)** (from Intel Labs) released with the paper [Vision Transformers for Dense Prediction](https://arxiv.org/abs/2103.13413) by René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
+1. **[EfficientFormer](model_doc/efficientformer)** (from Snap Research) released with the paper [EfficientFormer: Vision Transformers at MobileNetSpeed](https://arxiv.org/abs/2206.01191) by Yanyu Li, Geng Yuan, Yang Wen, Ju Hu, Georgios Evangelidis, Sergey Tulyakov, Yanzhi Wang, Jian Ren.
+1. **[EfficientNet](model_doc/efficientnet)** (from Google Brain) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://arxiv.org/abs/1905.11946) by Mingxing Tan, Quoc V. Le.
+1. **[ELECTRA](model_doc/electra)** (from Google Research/Stanford University) released with the paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://arxiv.org/abs/2003.10555) by Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
+1. **[EncoderDecoder](model_doc/encoder-decoder)** (from Google Research) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[ERNIE](model_doc/ernie)** (from Baidu) released with the paper [ERNIE: Enhanced Representation through Knowledge Integration](https://arxiv.org/abs/1904.09223) by Yu Sun, Shuohuan Wang, Yukun Li, Shikun Feng, Xuyi Chen, Han Zhang, Xin Tian, Danxiang Zhu, Hao Tian, Hua Wu.
+1. **[ErnieM](model_doc/ernie_m)** (from Baidu) released with the paper [ERNIE-M: Enhanced Multilingual Representation by Aligning Cross-lingual Semantics with Monolingual Corpora](https://arxiv.org/abs/2012.15674) by Xuan Ouyang, Shuohuan Wang, Chao Pang, Yu Sun, Hao Tian, Hua Wu, Haifeng Wang.
+1. **[ESM](model_doc/esm)** (from Meta AI) are transformer protein language models. **ESM-1b** was released with the paper [Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences](https://www.pnas.org/content/118/15/e2016239118) by Alexander Rives, Joshua Meier, Tom Sercu, Siddharth Goyal, Zeming Lin, Jason Liu, Demi Guo, Myle Ott, C. Lawrence Zitnick, Jerry Ma, and Rob Fergus. **ESM-1v** was released with the paper [Language models enable zero-shot prediction of the effects of mutations on protein function](https://doi.org/10.1101/2021.07.09.450648) by Joshua Meier, Roshan Rao, Robert Verkuil, Jason Liu, Tom Sercu and Alexander Rives. **ESM-2 and ESMFold** were released with the paper [Language models of protein sequences at the scale of evolution enable accurate structure prediction](https://doi.org/10.1101/2022.07.20.500902) by Zeming Lin, Halil Akin, Roshan Rao, Brian Hie, Zhongkai Zhu, Wenting Lu, Allan dos Santos Costa, Maryam Fazel-Zarandi, Tom Sercu, Sal Candido, Alexander Rives.
+1. **[FLAN-T5](model_doc/flan-t5)** (from Google AI) released in the repository [google-research/t5x](https://github.com/google-research/t5x/blob/main/docs/models.md#flan-t5-checkpoints) by Hyung Won Chung, Le Hou, Shayne Longpre, Barret Zoph, Yi Tay, William Fedus, Eric Li, Xuezhi Wang, Mostafa Dehghani, Siddhartha Brahma, Albert Webson, Shixiang Shane Gu, Zhuyun Dai, Mirac Suzgun, Xinyun Chen, Aakanksha Chowdhery, Sharan Narang, Gaurav Mishra, Adams Yu, Vincent Zhao, Yanping Huang, Andrew Dai, Hongkun Yu, Slav Petrov, Ed H. Chi, Jeff Dean, Jacob Devlin, Adam Roberts, Denny Zhou, Quoc V. Le, and Jason Wei
+1. **[FLAN-UL2](model_doc/flan-ul2)** (from Google AI) released in the repository [google-research/t5x](https://github.com/google-research/t5x/blob/main/docs/models.md#flan-ul2-checkpoints) by Hyung Won Chung, Le Hou, Shayne Longpre, Barret Zoph, Yi Tay, William Fedus, Eric Li, Xuezhi Wang, Mostafa Dehghani, Siddhartha Brahma, Albert Webson, Shixiang Shane Gu, Zhuyun Dai, Mirac Suzgun, Xinyun Chen, Aakanksha Chowdhery, Sharan Narang, Gaurav Mishra, Adams Yu, Vincent Zhao, Yanping Huang, Andrew Dai, Hongkun Yu, Slav Petrov, Ed H. Chi, Jeff Dean, Jacob Devlin, Adam Roberts, Denny Zhou, Quoc V. Le, and Jason Wei
+1. **[FlauBERT](model_doc/flaubert)** (from CNRS) released with the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://arxiv.org/abs/1912.05372) by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
+1. **[FLAVA](model_doc/flava)** (from Facebook AI) released with the paper [FLAVA: A Foundational Language And Vision Alignment Model](https://arxiv.org/abs/2112.04482) by Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, and Douwe Kiela.
+1. **[FNet](model_doc/fnet)** (from Google Research) released with the paper [FNet: Mixing Tokens with Fourier Transforms](https://arxiv.org/abs/2105.03824) by James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
+1. **[FocalNet](model_doc/focalnet)** (from Microsoft Research) released with the paper [Focal Modulation Networks](https://arxiv.org/abs/2203.11926) by Jianwei Yang, Chunyuan Li, Xiyang Dai, Lu Yuan, Jianfeng Gao.
+1. **[Funnel Transformer](model_doc/funnel)** (from CMU/Google Brain) released with the paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://arxiv.org/abs/2006.03236) by Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
+1. **[GIT](model_doc/git)** (from Microsoft Research) released with the paper [GIT: A Generative Image-to-text Transformer for Vision and Language](https://arxiv.org/abs/2205.14100) by Jianfeng Wang, Zhengyuan Yang, Xiaowei Hu, Linjie Li, Kevin Lin, Zhe Gan, Zicheng Liu, Ce Liu, Lijuan Wang.
+1. **[GLPN](model_doc/glpn)** (from KAIST) released with the paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://arxiv.org/abs/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
+1. **[GPT](model_doc/openai-gpt)** (from OpenAI) released with the paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) by Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever.
+1. **[GPT Neo](model_doc/gpt_neo)** (from EleutherAI) released in the repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) by Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy.
+1. **[GPT NeoX](model_doc/gpt_neox)** (from EleutherAI) released with the paper [GPT-NeoX-20B: An Open-Source Autoregressive Language Model](https://arxiv.org/abs/2204.06745) by Sid Black, Stella Biderman, Eric Hallahan, Quentin Anthony, Leo Gao, Laurence Golding, Horace He, Connor Leahy, Kyle McDonell, Jason Phang, Michael Pieler, USVSN Sai Prashanth, Shivanshu Purohit, Laria Reynolds, Jonathan Tow, Ben Wang, Samuel Weinbach
+1. **[GPT NeoX Japanese](model_doc/gpt_neox_japanese)** (from ABEJA) released by Shinya Otani, Takayoshi Makabe, Anuj Arora, and Kyo Hattori.
+1. **[GPT-2](model_doc/gpt2)** (from OpenAI) released with the paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) by Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever.
+1. **[GPT-J](model_doc/gptj)** (from EleutherAI) released in the repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) by Ben Wang and Aran Komatsuzaki.
+1. **[GPT-Sw3](model_doc/gpt-sw3)** (from AI-Sweden) released with the paper [Lessons Learned from GPT-SW3: Building the First Large-Scale Generative Language Model for Swedish](http://www.lrec-conf.org/proceedings/lrec2022/pdf/2022.lrec-1.376.pdf) by Ariel Ekgren, Amaru Cuba Gyllensten, Evangelia Gogoulou, Alice Heiman, Severine Verlinden, Joey Öhman, Fredrik Carlsson, Magnus Sahlgren.
+1. **[GPTBigCode](model_doc/gpt_bigcode)** (from BigCode) released with the paper [SantaCoder: don't reach for the stars!](https://arxiv.org/abs/2301.03988) by Loubna Ben Allal, Raymond Li, Denis Kocetkov, Chenghao Mou, Christopher Akiki, Carlos Munoz Ferrandis, Niklas Muennighoff, Mayank Mishra, Alex Gu, Manan Dey, Logesh Kumar Umapathi, Carolyn Jane Anderson, Yangtian Zi, Joel Lamy Poirier, Hailey Schoelkopf, Sergey Troshin, Dmitry Abulkhanov, Manuel Romero, Michael Lappert, Francesco De Toni, Bernardo García del Río, Qian Liu, Shamik Bose, Urvashi Bhattacharyya, Terry Yue Zhuo, Ian Yu, Paulo Villegas, Marco Zocca, Sourab Mangrulkar, David Lansky, Huu Nguyen, Danish Contractor, Luis Villa, Jia Li, Dzmitry Bahdanau, Yacine Jernite, Sean Hughes, Daniel Fried, Arjun Guha, Harm de Vries, Leandro von Werra.
+1. **[GPTSAN-japanese](model_doc/gptsan-japanese)** released in the repository [tanreinama/GPTSAN](https://github.com/tanreinama/GPTSAN/blob/main/report/model.md) by Toshiyuki Sakamoto(tanreinama).
+1. **[Graphormer](model_doc/graphormer)** (from Microsoft) released with the paper [Do Transformers Really Perform Bad for Graph Representation?](https://arxiv.org/abs/2106.05234) by Chengxuan Ying, Tianle Cai, Shengjie Luo, Shuxin Zheng, Guolin Ke, Di He, Yanming Shen, Tie-Yan Liu.
+1. **[GroupViT](model_doc/groupvit)** (from UCSD, NVIDIA) released with the paper [GroupViT: Semantic Segmentation Emerges from Text Supervision](https://arxiv.org/abs/2202.11094) by Jiarui Xu, Shalini De Mello, Sifei Liu, Wonmin Byeon, Thomas Breuel, Jan Kautz, Xiaolong Wang.
+1. **[Hubert](model_doc/hubert)** (from Facebook) released with the paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://arxiv.org/abs/2106.07447) by Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
+1. **[I-BERT](model_doc/ibert)** (from Berkeley) released with the paper [I-BERT: Integer-only BERT Quantization](https://arxiv.org/abs/2101.01321) by Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
+1. **[ImageGPT](model_doc/imagegpt)** (from OpenAI) released with the paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) by Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
+1. **[Informer](model_doc/informer)** (from Beihang University, UC Berkeley, Rutgers University, SEDD Company) released with the paper [Informer: Beyond Efficient Transformer for Long Sequence Time-Series Forecasting](https://arxiv.org/abs/2012.07436) by Haoyi Zhou, Shanghang Zhang, Jieqi Peng, Shuai Zhang, Jianxin Li, Hui Xiong, and Wancai Zhang.
+1. **[Jukebox](model_doc/jukebox)** (from OpenAI) released with the paper [Jukebox: A Generative Model for Music](https://arxiv.org/pdf/2005.00341.pdf) by Prafulla Dhariwal, Heewoo Jun, Christine Payne, Jong Wook Kim, Alec Radford, Ilya Sutskever.
+1. **[LayoutLM](model_doc/layoutlm)** (from Microsoft Research Asia) released with the paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://arxiv.org/abs/1912.13318) by Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
+1. **[LayoutLMv2](model_doc/layoutlmv2)** (from Microsoft Research Asia) released with the paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://arxiv.org/abs/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
+1. **[LayoutLMv3](model_doc/layoutlmv3)** (from Microsoft Research Asia) released with the paper [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://arxiv.org/abs/2204.08387) by Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei.
+1. **[LayoutXLM](model_doc/layoutxlm)** (from Microsoft Research Asia) released with the paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://arxiv.org/abs/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
+1. **[LED](model_doc/led)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LeViT](model_doc/levit)** (from Meta AI) released with the paper [LeViT: A Vision Transformer in ConvNet's Clothing for Faster Inference](https://arxiv.org/abs/2104.01136) by Ben Graham, Alaaeldin El-Nouby, Hugo Touvron, Pierre Stock, Armand Joulin, Hervé Jégou, Matthijs Douze.
+1. **[LiLT](model_doc/lilt)** (from South China University of Technology) released with the paper [LiLT: A Simple yet Effective Language-Independent Layout Transformer for Structured Document Understanding](https://arxiv.org/abs/2202.13669) by Jiapeng Wang, Lianwen Jin, Kai Ding.
+1. **[LLaMA](model_doc/llama)** (from The FAIR team of Meta AI) released with the paper [LLaMA: Open and Efficient Foundation Language Models](https://arxiv.org/abs/2302.13971) by Hugo Touvron, Thibaut Lavril, Gautier Izacard, Xavier Martinet, Marie-Anne Lachaux, Timothée Lacroix, Baptiste Rozière, Naman Goyal, Eric Hambro, Faisal Azhar, Aurelien Rodriguez, Armand Joulin, Edouard Grave, Guillaume Lample.
+1. **[Longformer](model_doc/longformer)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LongT5](model_doc/longt5)** (from Google AI) released with the paper [LongT5: Efficient Text-To-Text Transformer for Long Sequences](https://arxiv.org/abs/2112.07916) by Mandy Guo, Joshua Ainslie, David Uthus, Santiago Ontanon, Jianmo Ni, Yun-Hsuan Sung, Yinfei Yang.
+1. **[LUKE](model_doc/luke)** (from Studio Ousia) released with the paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://arxiv.org/abs/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
+1. **[LXMERT](model_doc/lxmert)** (from UNC Chapel Hill) released with the paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://arxiv.org/abs/1908.07490) by Hao Tan and Mohit Bansal.
+1. **[M-CTC-T](model_doc/mctct)** (from Facebook) released with the paper [Pseudo-Labeling For Massively Multilingual Speech Recognition](https://arxiv.org/abs/2111.00161) by Loren Lugosch, Tatiana Likhomanenko, Gabriel Synnaeve, and Ronan Collobert.
+1. **[M2M100](model_doc/m2m_100)** (from Facebook) released with the paper [Beyond English-Centric Multilingual Machine Translation](https://arxiv.org/abs/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
+1. **[MarianMT](model_doc/marian)** Machine translation models trained using [OPUS](http://opus.nlpl.eu/) data by Jörg Tiedemann. The [Marian Framework](https://marian-nmt.github.io/) is being developed by the Microsoft Translator Team.
+1. **[MarkupLM](model_doc/markuplm)** (from Microsoft Research Asia) released with the paper [MarkupLM: Pre-training of Text and Markup Language for Visually-rich Document Understanding](https://arxiv.org/abs/2110.08518) by Junlong Li, Yiheng Xu, Lei Cui, Furu Wei.
+1. **[Mask2Former](model_doc/mask2former)** (from FAIR and UIUC) released with the paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://arxiv.org/abs/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
+1. **[MaskFormer](model_doc/maskformer)** (from Meta and UIUC) released with the paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://arxiv.org/abs/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
+1. **[MatCha](model_doc/matcha)** (from Google AI) released with the paper [MatCha: Enhancing Visual Language Pretraining with Math Reasoning and Chart Derendering](https://arxiv.org/abs/2212.09662) by Fangyu Liu, Francesco Piccinno, Syrine Krichene, Chenxi Pang, Kenton Lee, Mandar Joshi, Yasemin Altun, Nigel Collier, Julian Martin Eisenschlos.
+1. **[mBART](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://arxiv.org/abs/2001.08210) by Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
+1. **[mBART-50](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://arxiv.org/abs/2008.00401) by Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
+1. **[MEGA](model_doc/mega)** (from Meta/USC/CMU/SJTU) released with the paper [Mega: Moving Average Equipped Gated Attention](https://arxiv.org/abs/2209.10655) by Xuezhe Ma, Chunting Zhou, Xiang Kong, Junxian He, Liangke Gui, Graham Neubig, Jonathan May, and Luke Zettlemoyer.
+1. **[Megatron-BERT](model_doc/megatron-bert)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[MGP-STR](model_doc/mgp-str)** (from Alibaba Research) released with the paper [Multi-Granularity Prediction for Scene Text Recognition](https://arxiv.org/abs/2209.03592) by Peng Wang, Cheng Da, and Cong Yao.
+1. **[mLUKE](model_doc/mluke)** (from Studio Ousia) released with the paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://arxiv.org/abs/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka.
+1. **[MobileBERT](model_doc/mobilebert)** (from CMU/Google Brain) released with the paper [MobileBERT: a Compact Task-Agnostic BERT for Resource-Limited Devices](https://arxiv.org/abs/2004.02984) by Zhiqing Sun, Hongkun Yu, Xiaodan Song, Renjie Liu, Yiming Yang, and Denny Zhou.
+1. **[MobileNetV1](model_doc/mobilenet_v1)** (from Google Inc.) released with the paper [MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications](https://arxiv.org/abs/1704.04861) by Andrew G. Howard, Menglong Zhu, Bo Chen, Dmitry Kalenichenko, Weijun Wang, Tobias Weyand, Marco Andreetto, Hartwig Adam.
+1. **[MobileNetV2](model_doc/mobilenet_v2)** (from Google Inc.) released with the paper [MobileNetV2: Inverted Residuals and Linear Bottlenecks](https://arxiv.org/abs/1801.04381) by Mark Sandler, Andrew Howard, Menglong Zhu, Andrey Zhmoginov, Liang-Chieh Chen.
+1. **[MobileViT](model_doc/mobilevit)** (from Apple) released with the paper [MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer](https://arxiv.org/abs/2110.02178) by Sachin Mehta and Mohammad Rastegari.
+1. **[MPNet](model_doc/mpnet)** (from Microsoft Research) released with the paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://arxiv.org/abs/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
+1. **[MT5](model_doc/mt5)** (from Google AI) released with the paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://arxiv.org/abs/2010.11934) by Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
+1. **[MVP](model_doc/mvp)** (from RUC AI Box) released with the paper [MVP: Multi-task Supervised Pre-training for Natural Language Generation](https://arxiv.org/abs/2206.12131) by Tianyi Tang, Junyi Li, Wayne Xin Zhao and Ji-Rong Wen.
+1. **[NAT](model_doc/nat)** (from SHI Labs) released with the paper [Neighborhood Attention Transformer](https://arxiv.org/abs/2204.07143) by Ali Hassani, Steven Walton, Jiachen Li, Shen Li, and Humphrey Shi.
+1. **[Nezha](model_doc/nezha)** (from Huawei Noah’s Ark Lab) released with the paper [NEZHA: Neural Contextualized Representation for Chinese Language Understanding](https://arxiv.org/abs/1909.00204) by Junqiu Wei, Xiaozhe Ren, Xiaoguang Li, Wenyong Huang, Yi Liao, Yasheng Wang, Jiashu Lin, Xin Jiang, Xiao Chen and Qun Liu.
+1. **[NLLB](model_doc/nllb)** (from Meta) released with the paper [No Language Left Behind: Scaling Human-Centered Machine Translation](https://arxiv.org/abs/2207.04672) by the NLLB team.
+1. **[NLLB-MOE](model_doc/nllb-moe)** (from Meta) released with the paper [No Language Left Behind: Scaling Human-Centered Machine Translation](https://arxiv.org/abs/2207.04672) by the NLLB team.
+1. **[Nyströmformer](model_doc/nystromformer)** (from the University of Wisconsin - Madison) released with the paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://arxiv.org/abs/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
+1. **[OneFormer](model_doc/oneformer)** (from SHI Labs) released with the paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
+1. **[OpenLlama](model_doc/open-llama)** (from [s-JoL](https://huggingface.co/s-JoL)) released on GitHub (now removed).
+1. **[OPT](master/model_doc/opt)** (from Meta AI) released with the paper [OPT: Open Pre-trained Transformer Language Models](https://arxiv.org/abs/2205.01068) by Susan Zhang, Stephen Roller, Naman Goyal, Mikel Artetxe, Moya Chen, Shuohui Chen et al.
+1. **[OWL-ViT](model_doc/owlvit)** (from Google AI) released with the paper [Simple Open-Vocabulary Object Detection with Vision Transformers](https://arxiv.org/abs/2205.06230) by Matthias Minderer, Alexey Gritsenko, Austin Stone, Maxim Neumann, Dirk Weissenborn, Alexey Dosovitskiy, Aravindh Mahendran, Anurag Arnab, Mostafa Dehghani, Zhuoran Shen, Xiao Wang, Xiaohua Zhai, Thomas Kipf, and Neil Houlsby.
+1. **[Pegasus](model_doc/pegasus)** (from Google) released with the paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/abs/1912.08777) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu.
+1. **[PEGASUS-X](model_doc/pegasus_x)** (from Google) released with the paper [Investigating Efficiently Extending Transformers for Long Input Summarization](https://arxiv.org/abs/2208.04347) by Jason Phang, Yao Zhao, and Peter J. Liu.
+1. **[Perceiver IO](model_doc/perceiver)** (from Deepmind) released with the paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://arxiv.org/abs/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
+1. **[PhoBERT](model_doc/phobert)** (from VinAI Research) released with the paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) by Dat Quoc Nguyen and Anh Tuan Nguyen.
+1. **[Pix2Struct](model_doc/pix2struct)** (from Google) released with the paper [Pix2Struct: Screenshot Parsing as Pretraining for Visual Language Understanding](https://arxiv.org/abs/2210.03347) by Kenton Lee, Mandar Joshi, Iulia Turc, Hexiang Hu, Fangyu Liu, Julian Eisenschlos, Urvashi Khandelwal, Peter Shaw, Ming-Wei Chang, Kristina Toutanova.
+1. **[PLBart](model_doc/plbart)** (from UCLA NLP) released with the paper [Unified Pre-training for Program Understanding and Generation](https://arxiv.org/abs/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
+1. **[PoolFormer](model_doc/poolformer)** (from Sea AI Labs) released with the paper [MetaFormer is Actually What You Need for Vision](https://arxiv.org/abs/2111.11418) by Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng.
+1. **[ProphetNet](model_doc/prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[QDQBert](model_doc/qdqbert)** (from NVIDIA) released with the paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://arxiv.org/abs/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius.
+1. **[RAG](model_doc/rag)** (from Facebook) released with the paper [Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks](https://arxiv.org/abs/2005.11401) by Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, Douwe Kiela.
+1. **[REALM](model_doc/realm.html)** (from Google Research) released with the paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://arxiv.org/abs/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang.
+1. **[Reformer](model_doc/reformer)** (from Google Research) released with the paper [Reformer: The Efficient Transformer](https://arxiv.org/abs/2001.04451) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
+1. **[RegNet](model_doc/regnet)** (from META Platforms) released with the paper [Designing Network Design Space](https://arxiv.org/abs/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
+1. **[RemBERT](model_doc/rembert)** (from Google Research) released with the paper [Rethinking embedding coupling in pre-trained language models](https://arxiv.org/abs/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
+1. **[ResNet](model_doc/resnet)** (from Microsoft Research) released with the paper [Deep Residual Learning for Image Recognition](https://arxiv.org/abs/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
+1. **[RoBERTa](model_doc/roberta)** (from Facebook), released together with the paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://arxiv.org/abs/1907.11692) by Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
+1. **[RoBERTa-PreLayerNorm](model_doc/roberta-prelayernorm)** (from Facebook) released with the paper [fairseq: A Fast, Extensible Toolkit for Sequence Modeling](https://arxiv.org/abs/1904.01038) by Myle Ott, Sergey Edunov, Alexei Baevski, Angela Fan, Sam Gross, Nathan Ng, David Grangier, Michael Auli.
+1. **[RoCBert](model_doc/roc_bert)** (from WeChatAI) released with the paper [RoCBert: Robust Chinese Bert with Multimodal Contrastive Pretraining](https://aclanthology.org/2022.acl-long.65.pdf) by HuiSu, WeiweiShi, XiaoyuShen, XiaoZhou, TuoJi, JiaruiFang, JieZhou.
+1. **[RoFormer](model_doc/roformer)** (from ZhuiyiTechnology), released together with the paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/abs/2104.09864) by Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu.
+1. **[RWKV](model_doc/rwkv)** (from Bo Peng), released on [this repo](https://github.com/BlinkDL/RWKV-LM) by Bo Peng.
+1. **[SegFormer](model_doc/segformer)** (from NVIDIA) released with the paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://arxiv.org/abs/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
+1. **[Segment Anything](model_doc/sam)** (from Meta AI) released with the paper [Segment Anything](https://arxiv.org/pdf/2304.02643v1.pdf) by Alexander Kirillov, Eric Mintun, Nikhila Ravi, Hanzi Mao, Chloe Rolland, Laura Gustafson, Tete Xiao, Spencer Whitehead, Alex Berg, Wan-Yen Lo, Piotr Dollar, Ross Girshick.
+1. **[SEW](model_doc/sew)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SEW-D](model_doc/sew_d)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SpeechT5](model_doc/speecht5)** (from Microsoft Research) released with the paper [SpeechT5: Unified-Modal Encoder-Decoder Pre-Training for Spoken Language Processing](https://arxiv.org/abs/2110.07205) by Junyi Ao, Rui Wang, Long Zhou, Chengyi Wang, Shuo Ren, Yu Wu, Shujie Liu, Tom Ko, Qing Li, Yu Zhang, Zhihua Wei, Yao Qian, Jinyu Li, Furu Wei.
+1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (from Facebook), released together with the paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
+1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (from Facebook), released together with the paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://arxiv.org/abs/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
+1. **[Splinter](model_doc/splinter)** (from Tel Aviv University), released together with the paper [Few-Shot Question Answering by Pretraining Span Selection](https://arxiv.org/abs/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
+1. **[SqueezeBERT](model_doc/squeezebert)** (from Berkeley) released with the paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://arxiv.org/abs/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer.
+1. **[SwiftFormer](model_doc/swiftformer)** (from MBZUAI) released with the paper [SwiftFormer: Efficient Additive Attention for Transformer-based Real-time Mobile Vision Applications](https://arxiv.org/abs/2303.15446) by Abdelrahman Shaker, Muhammad Maaz, Hanoona Rasheed, Salman Khan, Ming-Hsuan Yang, Fahad Shahbaz Khan.
+1. **[Swin Transformer](model_doc/swin)** (from Microsoft) released with the paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030) by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
+1. **[Swin Transformer V2](model_doc/swinv2)** (from Microsoft) released with the paper [Swin Transformer V2: Scaling Up Capacity and Resolution](https://arxiv.org/abs/2111.09883) by Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo.
+1. **[Swin2SR](model_doc/swin2sr)** (from University of Würzburg) released with the paper [Swin2SR: SwinV2 Transformer for Compressed Image Super-Resolution and Restoration](https://arxiv.org/abs/2209.11345) by Marcos V. Conde, Ui-Jin Choi, Maxime Burchi, Radu Timofte.
+1. **[SwitchTransformers](model_doc/switch_transformers)** (from Google) released with the paper [Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity](https://arxiv.org/abs/2101.03961) by William Fedus, Barret Zoph, Noam Shazeer.
+1. **[T5](model_doc/t5)** (from Google AI) released with the paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[T5v1.1](model_doc/t5v1.1)** (from Google AI) released in the repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[Table Transformer](model_doc/table-transformer)** (from Microsoft Research) released with the paper [PubTables-1M: Towards Comprehensive Table Extraction From Unstructured Documents](https://arxiv.org/abs/2110.00061) by Brandon Smock, Rohith Pesala, Robin Abraham.
+1. **[TAPAS](model_doc/tapas)** (from Google AI) released with the paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://arxiv.org/abs/2004.02349) by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos.
+1. **[TAPEX](model_doc/tapex)** (from Microsoft Research) released with the paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://arxiv.org/abs/2107.07653) by Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
+1. **[Time Series Transformer](model_doc/time_series_transformer)** (from HuggingFace).
+1. **[TimeSformer](model_doc/timesformer)** (from Facebook) released with the paper [Is Space-Time Attention All You Need for Video Understanding?](https://arxiv.org/abs/2102.05095) by Gedas Bertasius, Heng Wang, Lorenzo Torresani.
+1. **[Trajectory Transformer](model_doc/trajectory_transformers)** (from the University of California at Berkeley) released with the paper [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://arxiv.org/abs/2106.02039) by Michael Janner, Qiyang Li, Sergey Levine
+1. **[Transformer-XL](model_doc/transfo-xl)** (from Google/CMU) released with the paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://arxiv.org/abs/1901.02860) by Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
+1. **[TrOCR](model_doc/trocr)** (from Microsoft), released together with the paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://arxiv.org/abs/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
+1. **[TVLT](model_doc/tvlt)** (from UNC Chapel Hill) released with the paper [TVLT: Textless Vision-Language Transformer](https://arxiv.org/abs/2209.14156) by Zineng Tang, Jaemin Cho, Yixin Nie, Mohit Bansal.
+1. **[TVP](model_doc/tvp)** (from Intel) released with the paper [Text-Visual Prompting for Efficient 2D Temporal Video Grounding](https://arxiv.org/abs/2303.04995) by Yimeng Zhang, Xin Chen, Jinghan Jia, Sijia Liu, Ke Ding.
+1. **[UL2](model_doc/ul2)** (from Google Research) released with the paper [Unifying Language Learning Paradigms](https://arxiv.org/abs/2205.05131v1) by Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler
+1. **[UniSpeech](model_doc/unispeech)** (from Microsoft Research) released with the paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://arxiv.org/abs/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
+1. **[UniSpeechSat](model_doc/unispeech-sat)** (from Microsoft Research) released with the paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://arxiv.org/abs/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
+1. **[UPerNet](model_doc/upernet)** (from Peking University) released with the paper [Unified Perceptual Parsing for Scene Understanding](https://arxiv.org/abs/1807.10221) by Tete Xiao, Yingcheng Liu, Bolei Zhou, Yuning Jiang, Jian Sun.
+1. **[VAN](model_doc/van)** (from Tsinghua University and Nankai University) released with the paper [Visual Attention Network](https://arxiv.org/abs/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
+1. **[VideoMAE](model_doc/videomae)** (from Multimedia Computing Group, Nanjing University) released with the paper [VideoMAE: Masked Autoencoders are Data-Efficient Learners for Self-Supervised Video Pre-Training](https://arxiv.org/abs/2203.12602) by Zhan Tong, Yibing Song, Jue Wang, Limin Wang.
+1. **[ViLT](model_doc/vilt)** (from NAVER AI Lab/Kakao Enterprise/Kakao Brain) released with the paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://arxiv.org/abs/2102.03334) by Wonjae Kim, Bokyung Son, Ildoo Kim.
+1. **[Vision Transformer (ViT)](model_doc/vit)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[VisualBERT](model_doc/visual_bert)** (from UCLA NLP) released with the paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://arxiv.org/pdf/1908.03557) by Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
+1. **[ViT Hybrid](model_doc/vit_hybrid)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[ViTMAE](model_doc/vit_mae)** (from Meta AI) released with the paper [Masked Autoencoders Are Scalable Vision Learners](https://arxiv.org/abs/2111.06377) by Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
+1. **[ViTMSN](model_doc/vit_msn)** (from Meta AI) released with the paper [Masked Siamese Networks for Label-Efficient Learning](https://arxiv.org/abs/2204.07141) by Mahmoud Assran, Mathilde Caron, Ishan Misra, Piotr Bojanowski, Florian Bordes, Pascal Vincent, Armand Joulin, Michael Rabbat, Nicolas Ballas.
+1. **[Wav2Vec2](model_doc/wav2vec2)** (from Facebook AI) released with the paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://arxiv.org/abs/2006.11477) by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
+1. **[Wav2Vec2-Conformer](model_doc/wav2vec2-conformer)** (from Facebook AI) released with the paper [FAIRSEQ S2T: Fast Speech-to-Text Modeling with FAIRSEQ](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Sravya Popuri, Dmytro Okhonko, Juan Pino.
+1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (from Facebook AI) released with the paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://arxiv.org/abs/2109.11680) by Qiantong Xu, Alexei Baevski, Michael Auli.
+1. **[WavLM](model_doc/wavlm)** (from Microsoft Research) released with the paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://arxiv.org/abs/2110.13900) by Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
+1. **[Whisper](model_doc/whisper)** (from OpenAI) released with the paper [Robust Speech Recognition via Large-Scale Weak Supervision](https://cdn.openai.com/papers/whisper.pdf) by Alec Radford, Jong Wook Kim, Tao Xu, Greg Brockman, Christine McLeavey, Ilya Sutskever.
+1. **[X-CLIP](model_doc/xclip)** (from Microsoft Research) released with the paper [Expanding Language-Image Pretrained Models for General Video Recognition](https://arxiv.org/abs/2208.02816) by Bolin Ni, Houwen Peng, Minghao Chen, Songyang Zhang, Gaofeng Meng, Jianlong Fu, Shiming Xiang, Haibin Ling.
+1. **[X-MOD](model_doc/xmod)** (from Meta AI) released with the paper [Lifting the Curse of Multilinguality by Pre-training Modular Transformers](http://dx.doi.org/10.18653/v1/2022.naacl-main.255) by Jonas Pfeiffer, Naman Goyal, Xi Lin, Xian Li, James Cross, Sebastian Riedel, Mikel Artetxe.
+1. **[XGLM](model_doc/xglm)** (From Facebook AI) released with the paper [Few-shot Learning with Multilingual Language Models](https://arxiv.org/abs/2112.10668) by Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
+1. **[XLM](model_doc/xlm)** (from Facebook) released together with the paper [Cross-lingual Language Model Pretraining](https://arxiv.org/abs/1901.07291) by Guillaume Lample and Alexis Conneau.
+1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (from Facebook AI), released together with the paper [Unsupervised Cross-lingual Representation Learning at Scale](https://arxiv.org/abs/1911.02116) by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
+1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (from Facebook AI), released together with the paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://arxiv.org/abs/2105.00572) by Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
+1. **[XLM-V](model_doc/xlm-v)** (from Meta AI) released with the paper [XLM-V: Overcoming the Vocabulary Bottleneck in Multilingual Masked Language Models](https://arxiv.org/abs/2301.10472) by Davis Liang, Hila Gonen, Yuning Mao, Rui Hou, Naman Goyal, Marjan Ghazvininejad, Luke Zettlemoyer, Madian Khabsa.
+1. **[XLNet](model_doc/xlnet)** (from Google/CMU) released with the paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://arxiv.org/abs/1906.08237) by Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
+1. **[XLS-R](model_doc/xls_r)** (from Facebook AI) released with the paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://arxiv.org/abs/2111.09296) by Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
+1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (from Facebook AI) released with the paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://arxiv.org/abs/2006.13979) by Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
+1. **[YOLOS](model_doc/yolos)** (from Huazhong University of Science & Technology) released with the paper [You Only Look at One Sequence: Rethinking Transformer in Vision through Object Detection](https://arxiv.org/abs/2106.00666) by Yuxin Fang, Bencheng Liao, Xinggang Wang, Jiemin Fang, Jiyang Qi, Rui Wu, Jianwei Niu, Wenyu Liu.
+1. **[YOSO](model_doc/yoso)** (from the University of Wisconsin - Madison) released with the paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://arxiv.org/abs/2111.09714) by Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
+
+
+### Rangka kerja yang disokong
+
+Jadual di bawah mewakili sokongan semasa dalam perpustakaan untuk setiap model tersebut, sama ada model tersebut mempunyai Python
+tokenizer (dipanggil ""lambat""). Tokenizer ""pantas"" yang disokong oleh perpustakaan Tokenizers 🤗, sama ada mereka mempunyai sokongan dalam Jax (melalui
+Flax), PyTorch, dan/atau TensorFlow.
+
+
+
+| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
+|:-----------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
+| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| ALIGN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| AltCLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Audio Spectrogram Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Autoformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
+| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
+| BigBird-Pegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
+| BioGpt | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BiT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BLIP | ❌ | ❌ | ✅ | ✅ | ❌ |
+| BLIP-2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| BLOOM | ❌ | ✅ | ✅ | ❌ | ❌ |
+| BridgeTower | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Bros | ✅ | ✅ | ✅ | ❌ | ❌ |
+| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| CANINE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Chinese-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CLAP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
+| CLIPSeg | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CodeGen | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Conditional DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ConvNeXT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| ConvNeXTV2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CPM-Ant | ✅ | ❌ | ✅ | ❌ | ❌ |
+| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| CvT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecVision | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Deformable DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeiT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DETA | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DiNAT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| DonutSwin | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| EfficientFormer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| EfficientNet | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ERNIE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ErnieM | ✅ | ❌ | ✅ | ❌ | ❌ |
+| ESM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FLAVA | ❌ | ❌ | ✅ | ❌ | ❌ |
+| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
+| FocalNet | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| GIT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
+| GPT NeoX | ❌ | ✅ | ✅ | ❌ | ❌ |
+| GPT NeoX Japanese | ✅ | ❌ | ✅ | ❌ | ❌ |
+| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
+| GPT-Sw3 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| GPTBigCode | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPTSAN-japanese | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Graphormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GroupViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
+| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Informer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Jukebox | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
+| LayoutLMv3 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LeViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LiLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LLaMA | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LongT5 | ❌ | ❌ | ✅ | ❌ | ✅ |
+| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| M-CTC-T | ❌ | ❌ | ✅ | ❌ | ❌ |
+| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
+| MarkupLM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Mask2Former | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MaskFormerSwin | ❌ | ❌ | ❌ | ❌ | ❌ |
+| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MEGA | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Megatron-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MGP-STR | ✅ | ❌ | ✅ | ❌ | ❌ |
+| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MobileNetV1 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileNetV2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MVP | ✅ | ✅ | ✅ | ❌ | ❌ |
+| NAT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Nezha | ❌ | ❌ | ✅ | ❌ | ❌ |
+| NLLB-MOE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Nyströmformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OneFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| OpenLlama | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OPT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| OWL-ViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
+| PEGASUS-X | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Pix2Struct | ❌ | ❌ | ✅ | ❌ | ❌ |
+| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
+| REALM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ResNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RoBERTa-PreLayerNorm | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RoCBert | ✅ | ❌ | ✅ | ❌ | ❌ |
+| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RWKV | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SAM | ❌ | ❌ | ✅ | ✅ | ❌ |
+| SegFormer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
+| SpeechT5 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SwiftFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Swin Transformer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Swin Transformer V2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Swin2SR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SwitchTransformers | ❌ | ❌ | ✅ | ❌ | ❌ |
+| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Table Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Time Series Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TimeSformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Trajectory Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TVLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TVP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UPerNet | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VideoMAE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisionTextDualEncoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisualBERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ViT Hybrid | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
+| ViTMSN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
+| Wav2Vec2-Conformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Whisper | ✅ | ✅ | ✅ | ✅ | ✅ |
+| X-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| X-MOD | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XGLM | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| XLM-ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| YOLOS | ❌ | ❌ | ✅ | ❌ | ❌ |
+| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/_config.py b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/_config.py
new file mode 100644
index 0000000000000000000000000000000000000000..f49e4e4731965a504b8da443c2cd979638cd22bb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/_config.py
@@ -0,0 +1,14 @@
+# docstyle-ignore
+INSTALL_CONTENT = """
+# Transformers installation
+! pip install transformers datasets evaluate accelerate
+# To install from source instead of the last release, comment the command above and uncomment the following one.
+# ! pip install git+https://github.com/huggingface/transformers.git
+"""
+
+notebook_first_cells = [{"type": "code", "content": INSTALL_CONTENT}]
+black_avoid_patterns = {
+ "{processor_class}": "FakeProcessorClass",
+ "{model_class}": "FakeModelClass",
+ "{object_class}": "FakeObjectClass",
+}
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/_toctree.yml b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..d042168f7b9b693d92c0f85e2142ca1ec43e1236
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/_toctree.yml
@@ -0,0 +1,38 @@
+- sections:
+ - local: index
+ title: 🤗 Transformers
+ - local: quicktour
+ title: Tour rápido
+ - local: installation
+ title: Instalação
+ title: Início
+- sections:
+ - local: pipeline_tutorial
+ title: Pipelines para inferência
+ - local: training
+ title: Fine-tuning de um modelo pré-treinado
+ - local: accelerate
+ title: Treinamento distribuído com 🤗 Accelerate
+ title: Tutoriais
+- sections:
+ - local: fast_tokenizers
+ title: Usando os Tokenizers do 🤗 Tokenizers
+ - local: create_a_model
+ title: Criando uma arquitetura customizada
+ - local: custom_models
+ title: Compartilhando modelos customizados
+ - local: run_scripts
+ title: Treinamento a partir de um script
+ - local: converting_tensorflow_models
+ title: Convertendo checkpoints do TensorFlow para Pytorch
+ - local: serialization
+ title: Exportando modelos para ONNX
+ - sections:
+ - local: tasks/sequence_classification
+ title: Classificação de texto
+ - local: tasks/token_classification
+ title: Classificação de tokens
+ title: Fine-tuning para tarefas específicas
+ - local: multilingual
+ title: Modelos multilinguísticos para inferência
+ title: Guias práticos
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/accelerate.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/accelerate.md
new file mode 100644
index 0000000000000000000000000000000000000000..a4e346a2b4873ff475ff9c3e34ff75e276fb58a7
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/accelerate.md
@@ -0,0 +1,145 @@
+
+
+# Treinamento distribuído com o 🤗 Accelerate
+
+O paralelismo surgiu como uma estratégia para treinar modelos grandes em hardware limitado e aumentar a velocidade
+de treinamento em várias órdens de magnitude. Na Hugging Face criamos a biblioteca [🤗 Accelerate](https://huggingface.co/docs/accelerate)
+para ajudar os usuários a treinar modelos 🤗 Transformers com qualquer configuração distribuída, seja em uma máquina
+com múltiplos GPUs ou em múltiplos GPUs distribuidos entre muitas máquinas. Neste tutorial, você irá aprender como
+personalizar seu laço de treinamento de PyTorch para poder treinar em ambientes distribuídos.
+
+## Configuração
+
+De início, instale o 🤗 Accelerate:
+
+```bash
+pip install accelerate
+```
+
+Logo, devemos importar e criar um objeto [`Accelerator`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator).
+O `Accelerator` detectará automáticamente a configuração distribuída disponível e inicializará todos os
+componentes necessários para o treinamento. Não há necessidade portanto de especificar o dispositivo onde deve colocar seu modelo.
+
+```py
+>>> from accelerate import Accelerator
+
+>>> accelerator = Accelerator()
+```
+
+## Preparando a aceleração
+
+Passe todos os objetos relevantes ao treinamento para o método [`prepare`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator.prepare).
+Isto inclui os DataLoaders de treino e evaluação, um modelo e um otimizador:
+
+```py
+>>> train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
+... train_dataloader, eval_dataloader, model, optimizer
+... )
+```
+
+## Backward
+
+Por último, substitua o `loss.backward()` padrão em seu laço de treinamento com o método [`backward`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator.backward) do 🤗 Accelerate:
+
+```py
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... outputs = model(**batch)
+... loss = outputs.loss
+... accelerator.backward(loss)
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+Como se poder ver no seguinte código, só precisará adicionar quatro linhas de código ao seu laço de treinamento
+para habilitar o treinamento distribuído!
+
+```diff
++ from accelerate import Accelerator
+ from transformers import AdamW, AutoModelForSequenceClassification, get_scheduler
+
++ accelerator = Accelerator()
+
+ model = AutoModelForSequenceClassification.from_pretrained(checkpoint, num_labels=2)
+ optimizer = AdamW(model.parameters(), lr=3e-5)
+
+- device = torch.device("cuda") if torch.cuda.is_available() else torch.device("cpu")
+- model.to(device)
+
++ train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
++ train_dataloader, eval_dataloader, model, optimizer
++ )
+
+ num_epochs = 3
+ num_training_steps = num_epochs * len(train_dataloader)
+ lr_scheduler = get_scheduler(
+ "linear",
+ optimizer=optimizer,
+ num_warmup_steps=0,
+ num_training_steps=num_training_steps
+ )
+
+ progress_bar = tqdm(range(num_training_steps))
+
+ model.train()
+ for epoch in range(num_epochs):
+ for batch in train_dataloader:
+- batch = {k: v.to(device) for k, v in batch.items()}
+ outputs = model(**batch)
+ loss = outputs.loss
+- loss.backward()
++ accelerator.backward(loss)
+
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ progress_bar.update(1)
+```
+
+## Treinamento
+
+Quando tiver adicionado as linhas de código relevantes, inicie o treinamento por um script ou notebook como o Colab.
+
+### Treinamento em um Script
+
+Se estiver rodando seu treinamento em um Script, execute o seguinte comando para criar e guardar um arquivo de configuração:
+
+```bash
+accelerate config
+```
+
+Comece o treinamento com:
+
+```bash
+accelerate launch train.py
+```
+
+### Treinamento em um Notebook
+
+O 🤗 Accelerate pode rodar em um notebook, por exemplo, se estiver planejando usar as TPUs do Google Colab.
+Encapsule o código responsável pelo treinamento de uma função e passe-o ao `notebook_launcher`:
+
+```py
+>>> from accelerate import notebook_launcher
+
+>>> notebook_launcher(training_function)
+```
+
+Para obter mais informações sobre o 🤗 Accelerate e suas numerosas funções, consulte a [documentación](https://huggingface.co/docs/accelerate/index).
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/converting_tensorflow_models.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/converting_tensorflow_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..63e926d4dcfe6c2a8c65c112a37b0a42f77786d5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/converting_tensorflow_models.md
@@ -0,0 +1,152 @@
+
+
+# Convertendo checkpoints do TensorFlow para Pytorch
+
+Uma interface de linha de comando é fornecida para converter os checkpoints originais Bert/GPT/GPT-2/Transformer-XL/XLNet/XLM em modelos
+que podem ser carregados usando os métodos `from_pretrained` da biblioteca.
+
+
 +
+
+## Conteúdo
+
+A documentação é dividida em cinco partes:
+ - **INÍCIO** contém um tour rápido de instalação e instruções para te dar um empurrão inicial com os 🤗 Transformers.
+ - **TUTORIAIS** são perfeitos para começar a aprender sobre a nossa biblioteca. Essa seção irá te ajudar a desenvolver
+ habilidades básicas necessárias para usar o 🤗 Transformers.
+ - **GUIAS PRÁTICOS** irão te mostrar como alcançar um certo objetivo, como o fine-tuning de um modelo pré-treinado
+ para modelamento de idioma, ou como criar um cabeçalho personalizado para um modelo.
+ - **GUIAS CONCEITUAIS** te darão mais discussões e explicações dos conceitos fundamentais e idéias por trás dos modelos,
+ tarefas e da filosofia de design por trás do 🤗 Transformers.
+ - **API** descreve o funcionamento de cada classe e função, agrupada em:
+
+ - **CLASSES PRINCIPAIS** para as classes que expõe as APIs importantes da biblioteca.
+ - **MODELOS** para as classes e funções relacionadas à cada modelo implementado na biblioteca.
+ - **AUXILIARES INTERNOS** para as classes e funções usadas internamente.
+
+Atualmente a biblioteca contém implementações do PyTorch, TensorFlow e JAX, pesos para modelos pré-treinados e scripts de uso e conversão de utilidades para os seguintes modelos:
+
+### Modelos atuais
+
+
+
+1. **[ALBERT](model_doc/albert)** (from Google Research and the Toyota Technological Institute at Chicago) released with the paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://arxiv.org/abs/1909.11942), by Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
+1. **[BART](model_doc/bart)** (from Facebook) released with the paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://arxiv.org/abs/1910.13461) by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer.
+1. **[BARThez](model_doc/barthez)** (from École polytechnique) released with the paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321) by Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
+1. **[BARTpho](model_doc/bartpho)** (from VinAI Research) released with the paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701) by Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen.
+1. **[BEiT](model_doc/beit)** (from Microsoft) released with the paper [BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254) by Hangbo Bao, Li Dong, Furu Wei.
+1. **[BERT](model_doc/bert)** (from Google) released with the paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805) by Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova.
+1. **[BERTweet](model_doc/bertweet)** (from VinAI Research) released with the paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) by Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen.
+1. **[BERT For Sequence Generation](model_doc/bert-generation)** (from Google) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[BigBird-RoBERTa](model_doc/big_bird)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[Blenderbot](model_doc/blenderbot)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BlenderbotSmall](model_doc/blenderbot-small)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BORT](model_doc/bort)** (from Alexa) released with the paper [Optimal Subarchitecture Extraction For BERT](https://arxiv.org/abs/2010.10499) by Adrian de Wynter and Daniel J. Perry.
+1. **[ByT5](model_doc/byt5)** (from Google Research) released with the paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://arxiv.org/abs/2105.13626) by Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
+1. **[CamemBERT](model_doc/camembert)** (from Inria/Facebook/Sorbonne) released with the paper [CamemBERT: a Tasty French Language Model](https://arxiv.org/abs/1911.03894) by Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot.
+1. **[CANINE](model_doc/canine)** (from Google Research) released with the paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://arxiv.org/abs/2103.06874) by Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
+1. **[ConvNeXT](model_doc/convnext)** (from Facebook AI) released with the paper [A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545) by Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
+1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://arxiv.org/abs/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
+1. **[CLIP](model_doc/clip)** (from OpenAI) released with the paper [Learning Transferable Visual Models From Natural Language Supervision](https://arxiv.org/abs/2103.00020) by Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
+1. **[ConvBERT](model_doc/convbert)** (from YituTech) released with the paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496) by Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
+1. **[CPM](model_doc/cpm)** (from Tsinghua University) released with the paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://arxiv.org/abs/2012.00413) by Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
+1. **[CTRL](model_doc/ctrl)** (from Salesforce) released with the paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://arxiv.org/abs/1909.05858) by Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher.
+1. **[Data2Vec](model_doc/data2vec)** (from Facebook) released with the paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://arxiv.org/abs/2202.03555) by Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
+1. **[DeBERTa](model_doc/deberta)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[DeBERTa-v2](model_doc/deberta-v2)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[Decision Transformer](model_doc/decision_transformer)** (from Berkeley/Facebook/Google) released with the paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://arxiv.org/abs/2106.01345) by Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
+1. **[DiT](model_doc/dit)** (from Microsoft Research) released with the paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://arxiv.org/abs/2203.02378) by Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
+1. **[DeiT](model_doc/deit)** (from Facebook) released with the paper [Training data-efficient image transformers & distillation through attention](https://arxiv.org/abs/2012.12877) by Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
+1. **[DETR](model_doc/detr)** (from Facebook) released with the paper [End-to-End Object Detection with Transformers](https://arxiv.org/abs/2005.12872) by Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
+1. **[DialoGPT](model_doc/dialogpt)** (from Microsoft Research) released with the paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://arxiv.org/abs/1911.00536) by Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
+1. **[DistilBERT](model_doc/distilbert)** (from HuggingFace), released together with the paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://arxiv.org/abs/1910.01108) by Victor Sanh, Lysandre Debut and Thomas Wolf. The same method has been applied to compress GPT2 into [DistilGPT2](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), RoBERTa into [DistilRoBERTa](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), Multilingual BERT into [DistilmBERT](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation) and a German version of DistilBERT.
+1. **[DPR](model_doc/dpr)** (from Facebook) released with the paper [Dense Passage Retrieval for Open-Domain Question Answering](https://arxiv.org/abs/2004.04906) by Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih.
+1. **[DPT](master/model_doc/dpt)** (from Intel Labs) released with the paper [Vision Transformers for Dense Prediction](https://arxiv.org/abs/2103.13413) by René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
+1. **[EfficientNet](model_doc/efficientnet)** (from Google Research) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://arxiv.org/abs/1905.11946) by Mingxing Tan and Quoc V. Le.
+1. **[EncoderDecoder](model_doc/encoder-decoder)** (from Google Research) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[ELECTRA](model_doc/electra)** (from Google Research/Stanford University) released with the paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://arxiv.org/abs/2003.10555) by Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
+1. **[FlauBERT](model_doc/flaubert)** (from CNRS) released with the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://arxiv.org/abs/1912.05372) by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
+1. **[FNet](model_doc/fnet)** (from Google Research) released with the paper [FNet: Mixing Tokens with Fourier Transforms](https://arxiv.org/abs/2105.03824) by James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
+1. **[Funnel Transformer](model_doc/funnel)** (from CMU/Google Brain) released with the paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://arxiv.org/abs/2006.03236) by Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
+1. **[GLPN](model_doc/glpn)** (from KAIST) released with the paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://arxiv.org/abs/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
+1. **[GPT](model_doc/openai-gpt)** (from OpenAI) released with the paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) by Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever.
+1. **[GPT-2](model_doc/gpt2)** (from OpenAI) released with the paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) by Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever.
+1. **[GPT-J](model_doc/gptj)** (from EleutherAI) released in the repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) by Ben Wang and Aran Komatsuzaki.
+1. **[GPT Neo](model_doc/gpt_neo)** (from EleutherAI) released in the repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) by Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy.
+1. **[GPTSAN-japanese](model_doc/gptsan-japanese)** released in the repository [tanreinama/GPTSAN](https://github.com/tanreinama/GPTSAN/blob/main/report/model.md) by Toshiyuki Sakamoto(tanreinama).
+1. **[Hubert](model_doc/hubert)** (from Facebook) released with the paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://arxiv.org/abs/2106.07447) by Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
+1. **[I-BERT](model_doc/ibert)** (from Berkeley) released with the paper [I-BERT: Integer-only BERT Quantization](https://arxiv.org/abs/2101.01321) by Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
+1. **[ImageGPT](model_doc/imagegpt)** (from OpenAI) released with the paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) by Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
+1. **[LayoutLM](model_doc/layoutlm)** (from Microsoft Research Asia) released with the paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://arxiv.org/abs/1912.13318) by Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
+1. **[LayoutLMv2](model_doc/layoutlmv2)** (from Microsoft Research Asia) released with the paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://arxiv.org/abs/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
+1. **[LayoutXLM](model_doc/layoutxlm)** (from Microsoft Research Asia) released with the paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://arxiv.org/abs/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
+1. **[LED](model_doc/led)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[Longformer](model_doc/longformer)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LUKE](model_doc/luke)** (from Studio Ousia) released with the paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://arxiv.org/abs/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
+1. **[mLUKE](model_doc/mluke)** (from Studio Ousia) released with the paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://arxiv.org/abs/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka.
+1. **[LXMERT](model_doc/lxmert)** (from UNC Chapel Hill) released with the paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://arxiv.org/abs/1908.07490) by Hao Tan and Mohit Bansal.
+1. **[M2M100](model_doc/m2m_100)** (from Facebook) released with the paper [Beyond English-Centric Multilingual Machine Translation](https://arxiv.org/abs/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
+1. **[MarianMT](model_doc/marian)** Machine translation models trained using [OPUS](http://opus.nlpl.eu/) data by Jörg Tiedemann. The [Marian Framework](https://marian-nmt.github.io/) is being developed by the Microsoft Translator Team.
+1. **[Mask2Former](model_doc/mask2former)** (from FAIR and UIUC) released with the paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://arxiv.org/abs/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
+1. **[MaskFormer](model_doc/maskformer)** (from Meta and UIUC) released with the paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://arxiv.org/abs/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
+1. **[MBart](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://arxiv.org/abs/2001.08210) by Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
+1. **[MBart-50](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://arxiv.org/abs/2008.00401) by Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
+1. **[Megatron-BERT](model_doc/megatron-bert)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[MPNet](model_doc/mpnet)** (from Microsoft Research) released with the paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://arxiv.org/abs/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
+1. **[MT5](model_doc/mt5)** (from Google AI) released with the paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://arxiv.org/abs/2010.11934) by Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
+1. **[Nyströmformer](model_doc/nystromformer)** (from the University of Wisconsin - Madison) released with the paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://arxiv.org/abs/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
+1. **[OneFormer](model_doc/oneformer)** (from SHI Labs) released with the paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
+1. **[Pegasus](model_doc/pegasus)** (from Google) released with the paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/abs/1912.08777) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu.
+1. **[Perceiver IO](model_doc/perceiver)** (from Deepmind) released with the paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://arxiv.org/abs/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
+1. **[PhoBERT](model_doc/phobert)** (from VinAI Research) released with the paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) by Dat Quoc Nguyen and Anh Tuan Nguyen.
+1. **[PLBart](model_doc/plbart)** (from UCLA NLP) released with the paper [Unified Pre-training for Program Understanding and Generation](https://arxiv.org/abs/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
+1. **[PoolFormer](model_doc/poolformer)** (from Sea AI Labs) released with the paper [MetaFormer is Actually What You Need for Vision](https://arxiv.org/abs/2111.11418) by Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng.
+1. **[ProphetNet](model_doc/prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[QDQBert](model_doc/qdqbert)** (from NVIDIA) released with the paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://arxiv.org/abs/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius.
+1. **[REALM](model_doc/realm.html)** (from Google Research) released with the paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://arxiv.org/abs/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang.
+1. **[Reformer](model_doc/reformer)** (from Google Research) released with the paper [Reformer: The Efficient Transformer](https://arxiv.org/abs/2001.04451) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
+1. **[RemBERT](model_doc/rembert)** (from Google Research) released with the paper [Rethinking embedding coupling in pre-trained language models](https://arxiv.org/abs/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
+1. **[RegNet](model_doc/regnet)** (from META Platforms) released with the paper [Designing Network Design Space](https://arxiv.org/abs/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
+1. **[ResNet](model_doc/resnet)** (from Microsoft Research) released with the paper [Deep Residual Learning for Image Recognition](https://arxiv.org/abs/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
+1. **[RoBERTa](model_doc/roberta)** (from Facebook), released together with the paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://arxiv.org/abs/1907.11692) by Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
+1. **[RoFormer](model_doc/roformer)** (from ZhuiyiTechnology), released together with the paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/abs/2104.09864) by Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu.
+1. **[SegFormer](model_doc/segformer)** (from NVIDIA) released with the paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://arxiv.org/abs/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
+1. **[SEW](model_doc/sew)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SEW-D](model_doc/sew_d)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (from Facebook), released together with the paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
+1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (from Facebook), released together with the paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://arxiv.org/abs/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
+1. **[Splinter](model_doc/splinter)** (from Tel Aviv University), released together with the paper [Few-Shot Question Answering by Pretraining Span Selection](https://arxiv.org/abs/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
+1. **[SqueezeBert](model_doc/squeezebert)** (from Berkeley) released with the paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://arxiv.org/abs/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer.
+1. **[Swin Transformer](model_doc/swin)** (from Microsoft) released with the paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030) by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
+1. **[T5](model_doc/t5)** (from Google AI) released with the paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[T5v1.1](model_doc/t5v1.1)** (from Google AI) released in the repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[TAPAS](model_doc/tapas)** (from Google AI) released with the paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://arxiv.org/abs/2004.02349) by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos.
+1. **[TAPEX](model_doc/tapex)** (from Microsoft Research) released with the paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://arxiv.org/abs/2107.07653) by Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
+1. **[Transformer-XL](model_doc/transfo-xl)** (from Google/CMU) released with the paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://arxiv.org/abs/1901.02860) by Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
+1. **[TrOCR](model_doc/trocr)** (from Microsoft), released together with the paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://arxiv.org/abs/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
+1. **[UniSpeech](model_doc/unispeech)** (from Microsoft Research) released with the paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://arxiv.org/abs/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
+1. **[UniSpeechSat](model_doc/unispeech-sat)** (from Microsoft Research) released with the paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://arxiv.org/abs/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
+1. **[VAN](model_doc/van)** (from Tsinghua University and Nankai University) released with the paper [Visual Attention Network](https://arxiv.org/abs/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
+1. **[ViLT](model_doc/vilt)** (from NAVER AI Lab/Kakao Enterprise/Kakao Brain) released with the paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://arxiv.org/abs/2102.03334) by Wonjae Kim, Bokyung Son, Ildoo Kim.
+1. **[Vision Transformer (ViT)](model_doc/vit)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[ViTMAE](model_doc/vit_mae)** (from Meta AI) released with the paper [Masked Autoencoders Are Scalable Vision Learners](https://arxiv.org/abs/2111.06377) by Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
+1. **[VisualBERT](model_doc/visual_bert)** (from UCLA NLP) released with the paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://arxiv.org/pdf/1908.03557) by Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
+1. **[WavLM](model_doc/wavlm)** (from Microsoft Research) released with the paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://arxiv.org/abs/2110.13900) by Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
+1. **[Wav2Vec2](model_doc/wav2vec2)** (from Facebook AI) released with the paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://arxiv.org/abs/2006.11477) by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
+1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (from Facebook AI) released with the paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://arxiv.org/abs/2109.11680) by Qiantong Xu, Alexei Baevski, Michael Auli.
+1. **[XGLM](model_doc/xglm)** (From Facebook AI) released with the paper [Few-shot Learning with Multilingual Language Models](https://arxiv.org/abs/2112.10668) by Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
+1. **[XLM](model_doc/xlm)** (from Facebook) released together with the paper [Cross-lingual Language Model Pretraining](https://arxiv.org/abs/1901.07291) by Guillaume Lample and Alexis Conneau.
+1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (from Facebook AI), released together with the paper [Unsupervised Cross-lingual Representation Learning at Scale](https://arxiv.org/abs/1911.02116) by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
+1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (from Facebook AI), released together with the paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://arxiv.org/abs/2105.00572) by Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
+1. **[XLNet](model_doc/xlnet)** (from Google/CMU) released with the paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://arxiv.org/abs/1906.08237) by Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
+1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (from Facebook AI) released with the paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://arxiv.org/abs/2006.13979) by Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
+1. **[XLS-R](model_doc/xls_r)** (from Facebook AI) released with the paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://arxiv.org/abs/2111.09296) by Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
+1. **[YOSO](model_doc/yoso)** (from the University of Wisconsin - Madison) released with the paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://arxiv.org/abs/2111.09714) by Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
+
+
+### Frameworks aceitos
+
+A tabela abaixo representa a lista de suporte na biblioteca para cada um dos seguintes modelos, caso tenham um tokenizer
+do Python (chamado de "slow"), ou um tokenizer construído em cima da biblioteca 🤗 Tokenizers (chamado de "fast"). Além
+disso, são diferenciados pelo suporte em diferentes frameworks: JAX (por meio do Flax); PyTorch; e/ou Tensorflow.
+
+
+
+| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
+|:---------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
+| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
+| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
+| BigBirdPegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
+| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Canine | ✅ | ❌ | ✅ | ❌ | ❌ |
+| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
+| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ConvNext | ❌ | ❌ | ✅ | ✅ | ❌ |
+| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecVision | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeiT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
+| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
+| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
+| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
+| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
+| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MegatronBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| mT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Nystromformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Realm | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ResNet | ❌ | ❌ | ✅ | ❌ | ✅ |
+| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
+| SegFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
+| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Swin | ❌ | ❌ | ✅ | ❌ | ❌ |
+| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TAPEX | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| VisualBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
+| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XGLM | ✅ | ✅ | ✅ | ❌ | ✅ |
+| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XLMProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/installation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/installation.md
new file mode 100644
index 0000000000000000000000000000000000000000..f548736589ac0d81bc7ebe2d73d60652ce03040b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/pt/installation.md
@@ -0,0 +1,262 @@
+
+
+# Guia de Instalação
+
+Neste guia poderá encontrar informações para a instalação do 🤗 Transformers para qualquer biblioteca de
+Machine Learning com a qual esteja a trabalhar. Além disso, poderá encontrar informações sobre como gerar cachês e
+configurar o 🤗 Transformers para execução em modo offline (opcional).
+
+🤗 Transformers foi testado com Python 3.6+, PyTorch 1.1.0+, TensorFlow 2.0+, e Flax. Para instalar a biblioteca de
+deep learning com que deseja trabalhar, siga as instruções correspondentes listadas a seguir:
+
+* [PyTorch](https://pytorch.org/get-started/locally/)
+* [TensorFlow 2.0](https://www.tensorflow.org/install/pip)
+* [Flax](https://flax.readthedocs.io/en/latest/)
+
+## Instalação pelo Pip
+
+É sugerido instalar o 🤗 Transformers num [ambiente virtual](https://docs.python.org/3/library/venv.html). Se precisar
+de mais informações sobre ambientes virtuais em Python, consulte este [guia](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/).
+Um ambiente virtual facilitará a manipulação e organização de projetos e evita problemas de compatibilidade entre dependências.
+
+Comece criando um ambiente virtual no diretório do seu projeto:
+
+```bash
+python -m venv .env
+```
+
+E para ativar o ambiente virtual:
+
+```bash
+source .env/bin/activate
+```
+
+Agora É possível instalar o 🤗 Transformers com o comando a seguir:
+
+```bash
+pip install transformers
+```
+
+Somente para a CPU, é possível instalar o 🤗 Transformers e a biblioteca de deep learning respectiva apenas numa linha.
+
+Por exemplo, para instalar o 🤗 Transformers e o PyTorch, digite:
+
+```bash
+pip install transformers[torch]
+```
+
+🤗 Transformers e TensorFlow 2.0:
+
+```bash
+pip install transformers[tf-cpu]
+```
+
+🤗 Transformers e Flax:
+
+```bash
+pip install transformers[flax]
+```
+
+Por último, verifique se o 🤗 Transformers foi instalado com sucesso usando o seguinte comando para baixar um modelo pré-treinado:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('we love you'))"
+```
+
+Em seguida, imprima um rótulo e sua pontuação:
+
+```bash
+[{'label': 'POSITIVE', 'score': 0.9998704791069031}]
+```
+
+## Instalação usando a fonte
+
+Para instalar o 🤗 Transformers a partir da fonte use o seguinte comando:
+
+```bash
+pip install git+https://github.com/huggingface/transformers
+```
+
+O comando acima instalará a versão `master` mais atual em vez da última versão estável. A versão `master` é útil para
+utilizar os últimos updates contidos em 🤗 Transformers. Por exemplo, um erro recente pode ter sido corrigido somente
+após a última versão estável, antes que houvesse um novo lançamento. No entanto, há a possibilidade que a versão `master` não esteja estável.
+A equipa trata de mantér a versão `master` operacional e a maioria dos erros são resolvidos em poucas horas ou dias.
+Se encontrar quaisquer problemas, por favor abra um [Issue](https://github.com/huggingface/transformers/issues) para que o
+mesmo possa ser corrigido o mais rápido possível.
+
+Verifique que o 🤗 Transformers está instalado corretamente usando o seguinte comando:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('I love you'))"
+```
+
+## Instalação editável
+
+Uma instalação editável será necessária caso desejas um dos seguintes:
+* Usar a versão `master` do código fonte.
+* Contribuir ao 🤗 Transformers e precisa testar mudanças ao código.
+
+Para tal, clone o repositório e instale o 🤗 Transformers com os seguintes comandos:
+
+```bash
+git clone https://github.com/huggingface/transformers.git
+cd transformers
+pip install -e .
+```
+
+Estes comandos vão ligar o diretório para o qual foi clonado o repositório ao caminho de bibliotecas do Python.
+O Python agora buscará dentro dos arquivos que foram clonados além dos caminhos normais da biblioteca.
+Por exemplo, se os pacotes do Python se encontram instalados no caminho `~/anaconda3/envs/main/lib/python3.7/site-packages/`,
+o Python também buscará módulos no diretório onde clonamos o repositório `~/transformers/`.
+
+
 +